Amazon Web Services (AWS) is pleased to announce the successful completion of our Payment Card Industry (PCI) Data Security Standard (DSS) and Three Domain Secure (3DS) certifications. As part of this renewal, we have expanded the scope to include three additional AWS services and one additional AWS Region:
This certification means that customers can use these services while maintaining PCI DSS and PCI 3DS compliance, enabling innovation without compromising security. The full list of services can be found on the AWS Services in Scope by Compliance Program page.
The PCI DSS and PCI 3DS compliance packages include two key components for each certification:
Attestation of Compliance (AOC) – demonstrates that AWS was successfully validated against the PCI DSS and PCI 3DS standards.
AWS Responsibility Summary – provides guidance to help AWS customers understand their responsibility in developing and operating a highly secure environment on AWS for handling payment card data.
AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA).
This refreshed certification offers customers greater flexibility in deploying regulated workloads while reducing compliance overhead. Customers can access the PCI DSS and PCI 3DS report packages through AWS Artifact. This self-service portal provides on-demand access to AWS compliance reports, streamlining audit processes.
To learn more about our PCI programs and other compliance and security programs, see the AWS Compliance Programs page.
As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Amazon is sharing new findings about how a threat actor linked to the Democratic People’s Republic of Korea (DPRK) is targeting open source software libraries, the shared building blocks that companies around the world use to develop applications. Amazon Threat Intelligence has linked several recent compromises of popular Node Package Manager (NPM) libraries to the same DPRK-linked threat actor, a connection that hasn’t been publicly reported until now. The analysis also describes how generative AI is already changing what malicious software packages look like and how threat actors are beginning to probe AI-based code systems. We’re sharing this research to help the open source community and security teams better identify and address these types of events.
These developments come 2 years after the XZ Utils backdoor, which demonstrated how a patient attacker can compromise critical open source software by exploiting the trust and limited time of volunteer maintainers. Open source software underpins much of the internet’s infrastructure: operating systems, web servers, encryption libraries, and the application frameworks that businesses rely on daily. When an attacker compromises a widely used open source package, every organization that depends on that package is potentially affected. Since then, Amazon Threat Intelligence has observed the volume and sophistication of software supply chain attacks increase, driven in large part by DPRK‑linked threat actors and cybercriminal groups.
In this post, Amazon Threat Intelligence and the Amazon Inspector team share new details about recent campaigns against popular NPM packages, including evidence that the compromises of the axios, debug, chalk, and typo-crypto libraries were carried out by the same DPRK-linked threat actor tracked by the security community as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. We also outline how the techniques used to compromise open source repositories are evolving, why these changes matter for organizations that depend on open source software, and what Amazon Web Services (AWS) is doing to help customers detect and respond to these threats.
One DPRK–linked group behind multiple NPM compromises
In March 2025, the DPRK-linked threat actor compromised the typo-crypto package. In September 2025, the same threat actor compromised the debug and chalk NPM packages. In March 2026, the same operational playbook appeared in a compromise of the axios package, one of the most widely used JavaScript libraries with more than 100 million weekly downloads. In each case, the threat actor gained access by socially engineering a trusted maintainer of the package, then published a software update containing malicious code. Any organization that automatically pulled the latest version of these packages received the compromised update.
While the axios compromise has been publicly attributed to this DPRK-linked threat actor, the typo-crypto, debug, and chalk incidents haven’t previously been connected to it. Amazon Threat Intelligence identified shared tactics, techniques, and procedures (TTPs) across these supply-chain campaigns, including trojanized NPM packages, use of post-install hooks (scripts that run automatically when a package is installed), and code reuse. Based on analysis of command-and-control (C2) indicators and TTPs, Amazon Threat Intelligence assesses with medium confidence that these campaigns are attributable to the DPRK-linked threat actor tracked as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. This is the first time these compromises have been publicly tied to this DPRK-linked threat actor.
Amazon Threat Intelligence assesses this as part of a financially motivated pattern: by compromising a small number of highly popular packages, the group gains potential access to thousands of downstream environments simultaneously. For a financially motivated threat actor, this approach is far more efficient than targeting organizations one at a time.
The aggregate impact of these incidents underscores the efficiency of targeting share dependencies. As reported by Wiz Research, roughly 1 in 10 cloud environments were affected by the debug and chalk supply chain event within a two‑hour window.
A smaller campaign that foreshadowed later activity
During routine analysis of indicators and TTPs related to the axios threat actor, Amazon Threat Intelligence identified a connection to a domain registered in 2025, prompting a full investigation into its historical activity. That investigation uncovered that the same DPRK-linked threat actor had committed a trojanized file to the typo-crypto NPM package in March 2025. The malicious file, core.js, masquerades as the legitimate core-js NPM package within the typo-crypto repository.
Based on the limited number of observed downloads, Amazon Threat Intelligence assesses that this campaign was small scale and likely served as a testing ground for the more visible supply chain operations that followed in late 2025 and 2026. The group appears to have been refining supply chain techniques more than a year before the larger campaigns that drew public attention. Amazon Inspector reported this malware to the Open Source Vulnerabilities (OSV) database, where it’s now tracked as MAL‑2026‑3400, so that the broader security community can benefit from these findings.
The trojanized file executes when it receives a hash input beginning with the value 0098273. When triggered, it downloads a second-stage payload from a hardcoded C2 server, then executes the payload based on the victim’s operating system, with behavior tailored for Windows, macOS, or Linux. The malware implements file-based persistence with payload rotation and uses multi-layer obfuscation, combining base64‑encoded text with an XOR cipher keyed to 01042025.
Amazon Threat Intelligence assesses that the group was experimenting with techniques that later appeared in the higher-impact campaigns against axios, debug, and chalk. Although the observed download volume was low, the tradecraft aligns with what we later observed in attacks on more popular packages.
How attacker tradecraft is shifting
Over the past year, Amazon Threat Intelligence and Amazon Inspector have observed threat actors changing the techniques they use to target open source libraries. These changes matter because open source packages remain attractive targets: they’re widely trusted, automatically updated in many environments, and maintained by communities that welcome new contributors. The following patterns describe how attackers are adapting their methods to evade modern defenses. Each is designed to exploit the gap between the moment a dependency is inspected and the moment it actually executes. A year ago, we looked for malicious packages. Today, we look for malicious behaviors split across packages that appear harmless on their own.
From package‑level attacks to fragment‑level attacks
Amazon Inspector has observed attackers increasingly splitting a single malicious workflow across several ordinary-looking packages. One package stores an encrypted blob disguised as configuration. A second ships the decryption logic. A third, often published later, fetches and executes the payload.
Viewed on its own, each package looks benign. There are no install hooks that stand out, no obvious evaluation of untrusted input, no network calls that look suspicious. The malicious behavior only appears when the components are used together in the intended sequence. This approach is designed to defeat scanners that evaluate packages one by one instead of reasoning about how they interact in a real dependency graph.
Long-horizon campaigns that invest in trust
We’re also observing threat actors taking a long view of trust accumulation. Instead of publishing obvious malware and waiting for downloads, they publish something genuinely useful and maintain it. They behave like real maintainers for weeks or months, shipping features, fixing bugs, and gaining dependents.
The same patience shows up on the human side. In some cases, the goal isn’t to launch a new package at all, but to become a contributor to an existing project. That’s the through line from XZ Utils backdoor to the debug, chalk, and axios maintainer compromises. In each case, the adversary treated legitimacy as an asset to be spent once, at the moment of maximum access.
Decoupling the package from its behavior
In many recent cases, a library is clean on the public registry yet still dangerous, because its real behavior depends on resources the attacker controls elsewhere. These can include guard or license scripts fetched from an external repository at runtime, configuration files that gate certain behaviors, or remote endpoints consulted at startup.
As long as those external resources remain benign, code reviews pass and automated scans return clean results. When an attacker flips the content or arms an endpoint that previously returned a placeholder, every installed copy can become malicious at once, without any new package release. A package that shows no malicious behavior today isn’t the same as a package that’s is safe by design.
From basic obfuscation to real cryptography
Where attackers used to rely on simple obfuscation such as minification or single-layer base64 encoding, we now observe multi-stage payloads that use stronger cryptographic techniques. Examples include AES‑GCM encrypted blobs gated by passphrases, RC4-style string arrays with per-call keys, layered XOR over base64, and native loaders that hold the next stage as an encrypted field decrypted only in memory.
The common design choice is that the decryption key is never stored in the package itself. It’s derived from runtime context, fetched from a server at execution time, or supplied as a license key. That means even an analyst with full source access can’t reliably decrypt the payload statically. Stage one looks like a simple decryptor; the malicious content remains ciphertext until it runs on a real target with the real key.
Payloads that avoid detonating in sandboxes
As defenders have scaled automated analysis in cloud sandboxes, attackers have made their code more environment aware. The payload decides whether it’s being analyzed before it acts. We see execution gated behind real package install lifecycles, single-use environment variables, and checks for signals of a genuine developer or build environment. These include interactive terminals, realistic usernames and hostnames, domain membership, plausible uptime, local file history, specific operating systems, and cloud metadata that helps distinguish analysis infrastructure from normal workloads.
Some delivery servers also tailor what they serve based on the client. A benign decoy goes to generic browser-like requests, while the live payload only appears for the exact user agent used by the malware. The result is that a clean verdict from a cloud sandbox often tells you more about how convincing your environment looks than how safe the package is.
How generative AI is reshaping both attacks and defenses
Generative AI is changing what attackers can produce and what defenders can rely on. Adversaries can generate novel code and content at scale. Historically, many malicious packages were caught because they looked wrong, with broken language, thin documentation, obvious copy-paste, or a telltale function reused across samples. Generative AI erases many of those signals.
Attackers can now produce thousands of lines of coherent, idiomatic, well-commented code, complete with convincing documentation, plausible commit histories, and synthetic maintainer identities, wrapped around a backdoor. Because each variant can be mutated, renamed, restructured, and re-encrypted, there is no single stable signature to match. Pattern-based detection loses ground against malware that looks one of a kind in every deployment.
AI is also creating new initial access vectors. One emerging technique is slopsquatting, where attackers register package names that exist only because an AI coding assistant hallucinated them. When a developer or an autonomous coding agent asks for help and the model confidently recommends a nonexistent package, an attacker can pre-register that name and wait. The next person who follows the recommendation might receive malware, despite not mistyping anything or visiting a malicious site, because the AI effectively delivered the bad dependency for them. As organizations move toward agents that install dependencies with limited human review, this path looks less like a curiosity and more like a scalable delivery channel.
Most significantly, AI changes the calculus for defensive automation. Attackers are no longer just writing malware for humans to miss. They’re writing malware for AI reviewers to approve. As organizations rely on AI systems to review code and triage packages, those AI systems themselves become part of the attack surface. We expect that indirect prompt injection, a technique where hidden instructions manipulate an AI system into taking unintended actions, will increasingly be embedded in malicious packages to fool AI-based code scanners. These instructions can be hidden in source comments, README files, docstrings, or test fixtures, and crafted to convince an automated system to mark malicious code as safe, skip a specific file, or perform an unintended action during analysis. The same content the malware needs to function can carry a second, separate message aimed at the machine that inspects it.
How AWS is responding
We’re investing across Amazon Threat Intelligence and Amazon Inspector to help customers adapt to this shifting landscape of software supply chain risk. Amazon remains committed to helping protect the security of our customers and the internet by actively hunting for and mitigating threats from sophisticated threat actors. We will continue working with Amazon teams, industry partners, and the security community to share intelligence and mitigate threats. Upon discovering this campaign, Amazon Threat Intelligence worked with Amazon Inspector so the malicious package was tracked, mitigated, and shared with the community through the OSV database. Additionally, the observed indicators were shared with Amazon GuardDuty to alert our customers of this activity.
Amazon Inspector uses these insights to refine our detection logic, broaden coverage across registries, and prioritize signals that reflect the tradecraft shifts described in this post, and is collaborating with industry partners such as package registries and Open Source Security Foundation (OpenSSF) to share findings.
We’re also investing in helping open source maintainers better secure their projects. In 2026, AWS joined the Linux Foundation and other industry leaders to launch Akrites, a collaborative initiative to defend critical open source software against AI-enabled cyber threats. AWS has also jointly invested $12.5 million alongside other organizations to defend the open source ecosystem from AI-driven attacks. These efforts reflect a broader commitment: the security of open source software is a shared responsibility, and defending it requires sustained investment from the organizations that depend on it.
Our goal is to help customers understand where their environments rely on open source components, identify suspicious behavior early, and respond quickly when the software supply chain is used as an entry point.
Choosing the right cryptographic key management service on Amazon Web Services (AWS) starts with understanding the difference between AWS Key Management Service (AWS KMS) and AWS CloudHSM. Both provide key storage backed by a hardware security module (HSM) but serve very different needs. AWS KMS is a fully managed service that integrates with all AWS services and all AWS Regions, making it the right choice for most key management workloads. AWS CloudHSM is a specialized option for use cases where you have strict requirements for dedicated HSM instances or must support legacy applications built around traditional HSM interfaces.
Quick comparison
The following table shows the pricing, AWS Region availability, algorithms, and AWS service integrations as of July 2026.
Criteria
AWS KMS
AWS CloudHSM
Best for
Most cloud-based key management needs
Lift-and-shift from on-premises applications and use of legacy algorithms
Deployment
AWS managed HSMs, accessed through API endpoints
Customer managed HSMs, accessed through an Elastic Network Interface (ENI) in your virtual private cloud (VPC)
Cost
Pay per use (symmetric and RSA 2048 operations): $1 per key plus $0.03 per 10,000 requests per month
Pay by the hour (us-east-1): $1.60 per HSM instance per hour
AWS integration
All AWS services
Custom integration with AWS services
Region coverage
All AWS Regions
32 Regions
Quick decision guide
Choose AWS KMS for most use cases. Choose AWS CloudHSM only if you require:
Direct integration with third-party tools such as Microsoft SignTool, Nginx, and HAProxy that rely on traditional HSM interfaces, including: PKCS#11, Java Cryptographic Extension (JCE), OpenSSL Provider, and Key Storage Provider (KSP). These interfaces are required when your application is built to communicate with an HSM directly rather than through a cloud API.
Deprecated algorithms such as 3DES and PKCS#1 v1.5 with RSA. If you need to run less commonly used operations not supported by AWS KMS such as AES key wrapping and AES with CTR or CBC modes.
Shared benefits
AWS KMS and AWS CloudHSM both provide robust encryption key management capabilities that help organizations meet their security and compliance requirements. While each service offers distinct features tailored to different use cases, they share several core benefits that make them valuable tools for protecting sensitive data in the cloud.
Security
AWS KMS and AWS CloudHSM both provide tamper-resistant, HSM-based key management with physical data center controls. They secure administration and workloads with Transport Layer Security (TLS). Neither service allows AWS employees to access your key material. Both services deliver equivalent security through Federal Information Processing Standard (FIPS) 140-3 Level 3 validated hardware and enforce strict cryptographic isolation of customer keys. Compliance frameworks such as the ones listed below validate security based on cryptographic boundaries rather than hardware or partition dedication. The multi-tenant architecture of AWS KMS provides the same security guarantees as the single-tenant model used by AWS CloudHSM while reducing operational complexity and cost. Customer security teams consistently approve AWS KMS adoption after confirming that cryptographic isolation meets their single-tenant security and compliance requirements.
Regulatory compliance
AWS KMS and AWS CloudHSM meet major compliance certifications, including:
Federal Information Processing Standard (FIPS) 140-3 Level 3
Payment Card Industry Data Security Standard (PCI-DSS)
Health Insurance Portability and Accountability Act (HIPAA)
Federal Risk and Authorization Management Program (FedRAMP)
Both services protect data including personally identifiable information (PII) and Protected Health Information (PHI).
Standard algorithms
AWS KMS and AWS CloudHSM support standard cryptographic operations including AES-256, RSA, ECDSA, Ed25519, ECDH, ML-DSA, SHA-2, and HMAC. Both services are actively investing in post-quantum cryptography (PQC) to help customers prepare for future quantum computing threats and are committed to expanding PQC algorithm support as National Institute of Standards and Technology (NIST) standards are finalized.
Performance
AWS KMS supports a default request rate for cryptographic operations ranging from 10,000 transactions per second (TPS) to 100,000 TPS per account based on Region. You can request quota increases beyond the default limits. AWS CloudHSM requires explicit provisioning of additional instances for higher throughput. Customers typically provision at least one additional HSM instance to handle peak activity, which can be difficult to predict due to lack of utilization metrics.
Operational support
AWS KMS and AWS CloudHSM both support high availability, durability, automatic backup, and software patching. AWS KMS is a Regional service with high availability and durability provided without any customer management required. AWS CloudHSM is a zonal service with customers required to manage high availability and durability.
Given these shared capabilities, the choice of which service to use depends on your specific requirements. The following sections outline decision points to help you choose.
When to choose AWS KMS
AWS KMS offers a fully managed service that simplifies key management operations and reduces operational overhead compared to AWS CloudHSM. Organizations choose AWS KMS when they need seamless integration with AWS services, automatic key rotation, and a cost-effective solution that doesn’t require dedicated HSM management.
AWS integration
AWS KMS integrates with all AWS services across all major categories. These include AI platforms, storage, databases, and compute services. Most of these services support AWS KMS customer managed keys, giving you full control over the key using policies and access controls. For customers that value convenience over control, AWS services provide transparent encryption using AWS owned keys, eliminating the cost and lifecycle management overhead of customer-owned keys. Both customer managed and AWS owned keys are AWS KMS keys. AWS Identity and Access Management (IAM) enables least-privilege access controls, key policies to control access, and auditing all key usage through AWS CloudTrail.
Operational simplicity
AWS KMS handles all operational tasks including HSM instance provisioning and maintenance, automatic key rotation, auto-scaling, disaster recovery, and comprehensive audit logging. This eliminates the operational overhead required to maintain a solution based on AWS CloudHSM.
Cost considerations
AWS KMS costs $1 per month per key plus $0.03 per 10,000 requests (symmetric and RSA 2048 operations). AWS CloudHSM costs approximately $1.60 per hour per HSM (approximately $1,152 per month), excluding the operational overhead for staff to manage the cluster—which further favors AWS KMS for most workloads.
Break-even analysis:
Less than 500 million operations per month: AWS KMS typically costs 35–99% less
500 million–1 billion operations per month: Costs are comparable
More than 1 billion operations per month: AWS CloudHSM might be more cost-effective.
Note: Many AWS services cache Data Encryption Keys (DEKs) locally, significantly reducing the number of AWS KMS API calls. Actual AWS KMS costs at scale are often much lower than raw operation counts suggest. For example: A workload with 100 keys and 100 million monthly operations using two HSMs for high availability:
AWS CloudHSM: Approximately $2,304 per month for two HSMs plus operational costs
AWS KMS: $100 per month (keys) plus $300 per month in operational costs for a total of $400 per month
Savings using AWS KMS: $1904 per month (83% reduction)
Region coverage
AWS KMS operates in every AWS Region, including all commercial Regions, GovCloud, China Regions, and the European Sovereign Cloud Region. AWS CloudHSM operates in 34 Regions, and AWS evaluates each new Region individually for AWS CloudHSM support.
When to choose AWS CloudHSM
AWS CloudHSM provides HSM-specific interfaces and support for legacy cryptographic algorithms that aren’t available from AWS KMS.
Lift-and-shift on-premises workloads
AWS CloudHSM supports traditional HSM interfaces such as PKCS#11, JCE, OpenSSL, and KSP, simplifying migration to AWS with minimal application changes. AWS is actively expanding AWS KMS integration options for these workloads. Contact AWS Support to discuss current alternatives.
Legacy cryptographic algorithms
AWS CloudHSM supports deprecated algorithms such as 3DES and PKCS#1 v1.5 padding with RSA. It also supports less commonly used operations such as AES key wrapping and AES with CTR or CBC modes.
Conclusion
For most organizations, AWS KMS delivers enterprise-grade security with lower costs and zero operational overhead. Choose AWS CloudHSM only if you have specific requirements for traditional HSM interfaces or less commonly used algorithms and can justify the additional cost and operational complexity.
Ready to get started? Use these guides to implement your chosen solution:
The new IRAP report includes four additional AWS services that are now assessed at the PROTECTED level under IRAP. This brings the total number of services assessed at the PROTECTED level to 167.
We have developed an IRAP documentation pack to help our Australian customers and their partners plan, architect, and assess risk for their workloads when they use AWS cloud services.
The IRAP pack on AWS Artifact also includes newly updated versions of the AWS Consumer Guide and the whitepaper Reference Architectures for ISM PROTECTED Workloads in the AWS Cloud.
Reach out to your AWS representatives to let us know which additional services you want to see in scope for upcoming IRAP assessments. We strive to bring more services into scope at the PROTECTED level under IRAP to support your requirements.
AWS Security Assurance Services is announcing the release of the Cloud Security Alliance (CSA) Compliance Guide on Amazon Web Service (AWS), a new resource that maps the 17 control domains and 207 control objectives of the Cloud Controls Matrix v4.1 (CCM) to AWS services and recommended implementation practices. The guide is intended to help organizations using AWS plan, implement, and evidence the controls relevant to their CCM scope, including those pursuing or maintaining CSA STAR certification.
What is the Cloud Controls Matrix?
The Cloud Security Alliance is a not-for-profit organization dedicated to defining and raising awareness of best practices for cloud security. AWS maintains CSA STAR Level 2 certification, which couples the requirements of ISO/IEC 27001:2022 with the CCM. The CSA STAR documentation and the AWS Consensus Assessments Initiative Questionnaire (CAIQ) are available to AWS customers through AWS Artifact.
The CSA Cloud Controls Matrix is a cybersecurity controls framework developed by the CSA that provides a detailed set of security controls mapped across multiple domains (such as audit and assurance, identity and access management, and encryption and key management) specifically designed to assess and manage security risks in cloud computing environments. The CCM is cloud agnostic, designed to be applicable to any cloud service provider or deployment model, such as infrastructure as a service (IaaS), platform as a service (PaaS), and software as a service (SaaS), regardless of the underlying technology or vendor, providing universal security controls that organizations can apply across cloud platforms.
Responsibility models
CCM defines its own Shared Security Responsibility Model (SSRM) with three categories: Cloud service provider (CSP)-owned, customer-owned, and shared (independent or dependent). The guide recommends using the SSRM together with the AWS Shared Responsibility Model. For controls that AWS owns, the guide points to AWS attestations available through AWS Artifact (for example, SOC reports, ISO certificates, and the CSA STAR attestation) as inherited evidence. For controls that customers own or share, the guide describes how to implement and evidence them using AWS services. Using a CSA STAR–certified AWS service doesn’t by itself make a customer workload compliant. Customers remain responsible for configuring services, managing access, protecting data, and implementing additional controls based on their environment, risk assessments, and regulatory obligations. The guide is informational and doesn’t replace the AWS compliance documentation and certifications available through AWS Artifact.
What’s inside the guide
For each control, the guide states applicability, describes how organizations can implement the control on AWS, identifies common pitfalls, and lists examples that can be used as evidence during an assessment.
Black Hat 2026 (Aug 1-6, 2026) brings together over 22,000 security practitioners, researchers, and CISOs who build, break, and defend enterprise infrastructure. They’re security professionals who push the limits of offensive and defensive security and demand proof over promises. As frontier security models like Mythos reshape the enterprise landscape, they need security that operates at the same speed as the events they face. This August, Amazon Web Services (AWS) returns to Las Vegas to meet with our customers and partners to show how we’re delivering enterprise security at machine speed.
At Black Hat USA 2026, connect with AWS through live demos, a practitioner session on autonomous security operations, and an executive roundtable on building durable AI security architectures, plus networking receptions with customers and partners. Here’s where to find us and what you’ll take away.
Experience AWS security innovation in action
Visit us at Booth #1648 to explore five interactive demo pedestals, each aligned to a pillar of our AI-powered security story:
Post-Mythos enterprise security: AWS uses multiple frontier AI reasoning models to find issues, validate exploitability, and autonomously fix exposures, compressing mean-time-to-remediation from days to minutes. Learn how AWS Continuum helps you find risks before you ship, prioritize by real business impact, and remediate at machine speed while you stay in control.
AI-powered investigations: Amazon GuardDuty AI-powered investigations automatically analyze findings and the accounts around them to separate true threats from benign activity at scale. Drawing on log activity, resource configuration, internet reachability, and historical findings, it delivers triage reports that match expert-level accuracy, freeing your team to focus on what matters.
Purpose-built AI workload security: AWS extends the enterprise security controls you already trust to address the unique demands of AI workloads. Amazon Bedrock helps you build and deploy generative AI applications, with hundreds of top foundation models plus built-in safety controls, guardrails, and evaluation tools. Amazon Bedrock AgentCore Identity keeps you in full control of what your AI agents can access.
Full-stack multicloud security: AWS Security Hub Extended delivers full-stack security by integrating AWS services with 21 curated partner solutions across nine categories, from endpoint and identity to AI, with pay-as-you-go pricing, one console, and one bill. All findings flow in OCSF format with zero integration work, and a risk correlation engine traces paths across multicloud so your team fixes root causes rather than chasing symptoms.
AWS Partner solutions: A dedicated partner demo pedestal runs live demonstrations from select AWS Partners, showing how their solutions integrate with AWS to address your most critical security challenges. With over 25 partners rotating throughout Business Hall hours, you get a firsthand view of how these integrations work together to strengthen your security posture.
Theater sessions: Want to go deeper on a specific topic without committing to a full session? During expo hours, our theater hosts 15-minute AWS and partner talks curated around the challenges enterprise security teams face today. Topics range from enabling AI adoption securely, to unifying visibility across clouds, to automating response. Subject matter experts from AWS and our partners lead each session and give you insights you can bring back to your team. Featured sessions include:
From finding to fix at machine speed with AWS Continuum
Securing the agentic AI stack
Architecting defense-in-depth for AI workloads
Network security strategies for the post-Mythos era
One console for unified full-stack security
For the latest theater session schedule, including dates and times, visit AWS at Black Hat 2026.
Engagement Zone: Take a quick break and test your detection skills in a gamified, hands-on challenge. Race the clock to resolve security issues and collect power-ups that speed your mission to secure the environment. Rack up your score, lock in your percentile rank, and see how you stack up against every other player.
Beyond the booth: Sessions and executive roundtable
AWS security experts share insights at speaking sessions and host an executive roundtable at Black Hat USA 2026.
Speaking Session | Machine-Speed Defense: Building an Autonomous Security Operations Loop for the AI Era Wednesday, August 5, 10:15–10:35 AM PDT Pulse Stage 2 In a post-Mythos world, organizations need to use AI-powered reasoning to discover, correlate, validate, and remediate security exposures at machine speed. This session provides a blueprint for building an autonomous security operations loop, using business-context graphs and sandbox validation, to unlock machine-speed defense as a durable competitive edge.
Executive Roundtable | Autonomous Defense at Cloud Scale: Critical Choices for Security Leaders Today Wednesday, August 5, 11:00 AM–12:00 PM PDT Breakers F As agentic AI and frontier models reshape the threat landscape, foundational security remains essential, and organizations that layer autonomous workload governance on top can turn AI into a true security force multiplier. This executive roundtable explores how to build a durable, adaptive security harness that accounts for the real economics of AI-powered defense and evolves alongside rapidly advancing models and techniques.
Briefing | ThreatForest: Automated Attack Trees from Source Code Thursday, August 6, 2:35–3:15 PM PDT Jasmine, Level 3 Threat modeling is critical, but manual processes can’t keep pace with cloud-focused architectures. This briefing will dive into how ThreatForest uses six specialized AI agents to automatically analyze source code and produce validated attack trees mapped to MITRE ATT&CK with actionable mitigations. Attendees walk away with the open source tool and a reusable multi-agent architecture pattern.
AWS activities and events
Beyond the expo floor, AWS hosts a portfolio of ancillary events built for focused conversations and networking across the security community. Join us at:
Catch Security LIVE! on-site at Mandalay Bay on Wednesday, August 5 and Thursday, August 6. This infotainment-style broadcast brings AWS and AWS Partners together to solve real security challenges for customers across 20-minute conversational segments, covering everything from data protection and compliance to application and perimeter security. With over 30 segments, Security LIVE! showcases the breadth of the AWS security partner ecosystem. Stop by the set to watch it unfold live.
Join us in Las Vegas
Whether you’re exploring how to secure AI workloads, adopting autonomous remediation as frontier models like Mythos reshape the landscape, or unifying security across domains and clouds, the AWS team at Black Hat USA 2026 is ready to help.
Amazon Web Services (AWS) successfully completed an onboarding audit with no findings for ISO 9001:2015, 27001:2022, 27017:2015, 27018:2019, 27701:2019, 20000-1:2018, and 22301:2019, and Cloud Security Alliance (CSA) STAR Cloud Controls Matrix (CCM) v4.0. EY Certify Point auditors conducted the audit and reissued the certificates on May 31, 2026. The objective of the audit was to enable AWS to expand their ISO and CSA STAR certifications to include two additional services. The ISO standards cover areas including quality management, information security, cloud security, privacy protection, service management, and business continuity. The certifications demonstrate AWS’s commitment to maintaining robust security controls and protecting customer data across our services.
During this onboarding audit, we added two additional AWS services to the scope since the last certification issued on February 25, 2026. Following are the two additional services:
For a full list of AWS services that are certified under ISO and CSA Star, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the AWS Management Console through AWS Artifact.
If you have feedback about this post, submit comments in the Comments section below.
If you’re running Apache Solr for search, now is a great time to migrate to Amazon OpenSearch Service. Amazon OpenSearch Serverless offers a modern, managed destination that greatly reduces operational overhead. Migration Assistant for Amazon OpenSearch Service now supports Apache Solr sources from versions 6.x through 9.x. Migration Assistant now includes an AI assistant that you can drive from your preferred AI tools. The assistant walks you through the migration, providing a detailed report with timelines, blockers, schema and query translation.
In this post, you will learn why now is the time to take advantage of the ease of operations and native AI capabilities of OpenSearch Serverless, and migrate from Solr.
The challenge of managing Solr
Many organizations have Solr deployments that have run for years, carrying accumulated technical debt: older versions, custom patches, and operational processes originating with engineers who have left. Running Solr in production requires ongoing investment in upgrades, security patches, monitoring, failure recovery, and capacity planning. The operational burden compounds as your deployment ages and the engineers who built it move on, leaving the remaining team with a system that is difficult to modify safely.
Meanwhile, search has evolved. Users interact through chat interfaces and AI agents that synthesize information on their behalf. These patterns require semantic understanding, hybrid retrieval, and agentic capabilities like memory and Model Context Protocol (MCP) support. OpenSearch is an open source software suite for search, analytics, and observability, licensed under the Apache License V2.0 and based on Apache Lucene. OpenSearch provides a broad and deep set of vector capabilities for AI workloads: multiple engines (Facebook AI Similarity Search (FAISS) and Lucene), multiple algorithms (Hierarchical Navigable Small World (HNSW) and Inverted File (IVF)), quantization for cost management, hybrid search with score normalization, neural sparse search, and a connector framework. You can use the OpenSearch connector framework to connect to your own models hosted in services such as Amazon Bedrock and Amazon SageMaker. With these capabilities, you can build chat-based search, power AI agents, and implement Retrieval Augmented Generation (RAG) workflows on your search engine.
Technical debt in custom patches and undocumented procedures can make shipping new features on Solr slow and risky. OpenSearch Serverless provides a modern engine with all the capabilities just mentioned, along with automatic scaling, and minimal infrastructure to maintain. Even if you remain focused on traditional search, OpenSearch Serverless delivers relevant results with less operational effort.
OpenSearch Serverless simplifies search
Amazon OpenSearch Serverless alleviates infrastructure provisioning, capacity planning, and data lifecycle management. You create a collection, send data, and run queries. OpenSearch Serverless automatically matches compute to your workload, independently scaling up indexing and search compute during spikes, and scaling compute to zero when idle. You pay only for storage when no requests are being processed. For variable traffic patterns, OpenSearch Serverless can cost up to 60% less than an OpenSearch Service domain provisioned for peak.
The vector engine supports HNSW and IVF with FAISS and Lucene, plus quantization techniques to manage cost as your collection grows. With Automatic Semantic Enrichment, you can enable a sparse model with a single setting to augment text with vectors and improve relevance without building an embedding pipeline. GPU acceleration reduces HNSW index build times from hours to minutes. OpenSearch Serverless also supports agents and RAG workflows.
If your workload requires tight control over infrastructure: specific instance types, custom plugin configurations, or extreme scale beyond what serverless deployments target, Amazon OpenSearch Service domains are the alternative destination. Domains give you full control over the cluster with one-click provisioning, patching, and backups. Migration Assistant supports both destinations, so you can pick the deployment model that fits your workload without changing your migration approach.
Migration Assistant for Amazon OpenSearch Service
Migration Assistant has helped customers move from self-managed Elasticsearch and OpenSearch to OpenSearch Service since December 2023. It now supports Solr sources. Migration Assistant now includes an AI-assisted experience that you can drive from your preferred AI tools, like Kiro, Claude Code, and others, to plan a migration, deploy the necessary infrastructure, and execute both historical and live traffic migration.
Historically, migrations required weeks of planning and assessments before any data movement could begin, and the process was often error-prone. The AI-assisted experience provides an agent-guided workflow that helps you structure, execute, and validate your migration faster and more reliably. You can use Migration Assistant itself to do your assessment, or connect with the skills in the AWS Model Context Protocol (MCP) server. Migration Assistant also now supports live traffic capture and replay for Solr, so you can validate the new environment with real workloads before cutting over.
Migration Assistant supports migrations to OpenSearch Serverless and OpenSearch Service domains from a range of Solr, Elasticsearch, and OpenSearch versions. It’s open source, so you can use it for migrating to OpenSearch Serverless in all commercial AWS Regions and AWS GovCloud (US) Regions where OpenSearch Serverless is available.
Migrate now
OpenSearch Serverless gives you vector, hybrid, and semantic search, automatic scaling, scale-to-zero compute, and zero operational overhead. Migration Assistant for Amazon OpenSearch Service provides the AI-assisted tools to get there: plan with the agent, deploy the infrastructure, run a backfill from your Solr backups, and validate with live traffic capture and replay before you cut over. Start by pointing your AI tool of choice to Migration Assistant to get a plan, timeline, and cost estimate.
Read all about the latest AWS security features, compliance updates, and hands-on resources in our new, monthly digest posts. You’ll find expert blog posts, new service capabilities, code samples, and workshops.
AWS Security Blog posts
This month’s AWS Security Blog posts covered identity and access management, threat intelligence, network security, AI-powered security tooling, and multi-account governance. Read on for guidance on restricting console access to expected networks, securing multi-tenant AI agents, preventing data exfiltration, and managing organization-scale migrations.
Amazon Cognito unlocks advanced capabilities with next-generation infrastructure Authors: Howie Li, Georgi Baghdasaryan | Published: June 4, 2026 Amazon Cognito introduced high-throughput performance, customer-managed keys for data encryption at rest, and multi-Region replication for business continuity, built on a new storage infrastructure migrated with zero downtime.
Threat tactic spotlight: Subdomain takeover Authors: Matt Gurr, Ariam Michael, Geoff Sweet, Luis Pastor | Published: June 16, 2026 Learn to detect and prevent subdomain takeover using AWS Config custom rules to identify dangling DNS CNAME records pointing to deleted resources in globally shared namespaces
Introducing AWS Continuum: Security at machine speed Authors: Chet Kapoor | Published: June 17, 2026 AWS Continuum for code vulnerabilities is an AI-native platform that addresses the full lifecycle of a code vulnerability at machine speed—from discovery and prioritization through validation and remediation.
Accelerate security investigations with Kiro CLI Authors: Sibasankar Behera, Marshall Jones | Published: June 18, 2026 Learn to use Kiro CLI to conduct security investigations following the AWS Security Incident Response Guide framework, from triaging Amazon GuardDuty findings through containment and evidence preservation.
What the June 2026 Threat Technique Catalog update means for your AWS environment Authors: Shannon Brazil, Cydney Stude, Javier Teitelbaum | Published: June 29, 2026 Learn about five new entries and three updates to the Threat Technique Catalog for AWS, covering container security, organization-level trust, and compute hijacking patterns observed by AWS CIRT.
Data protection
Identify unused AWS KMS keys and prevent accidental key deletions Authors: Andrea Rossi, Poojil Tripathi | Published: June 2, 2026 Learn to use the new AWS KMS GetKeyLastUsage API to audit key activity, identify unused keys, and apply policy controls that prevent accidental deletion of recently used keys.
Governance and compliance
From Monolith to Multi-Account: Pinterest’s AWS Organization Transformation Journey Authors: Sid Vantair, James Fogel, Jeremy Talis | Published: June 4, 2026 Learn how Pinterest migrated from a single monolithic AWS account to a multi-account architecture, including management account separation, automated account provisioning, and centralized networking.
This month brings 10 new AWS samples spanning AI security, identity, infrastructure security, governance, and observability. From securing Amazon Bedrock AgentCore agents with AWS WAF to building graph-based CMDBs for dependency analysis, these repositories help you implement security and governance best practices across your AWS environment.
AI Security Posture Management (AI SPM) on AWS Learn to discover, assess, and protect AI agents running in your environment using AWS-native services across three pillars: observe, govern, and defend, with rules mapped to OWASP LLM Top 10, NIST AI RMF, and MITRE ATLAS.
Bedrock Ops Lens Learn to deploy an Amazon Bedrock observability dashboard in your own account for per-account, per-model, and per-tag cost attribution, quota tracking, latency monitoring, and model lifecycle management, with an MCP server for IDE access.
AWS Agent Registry sample demo application Learn to use AWS Agent Registry to publish, review, approve, and discover AI agents, MCP servers, and agent skills through a centralized catalog with governance workflows.
OpenAI Codex through Amazon Bedrock — Usage governance with LiteLLM Learn to centrally govern, administer, and monitor OpenAI Codex access for engineering teams using Amazon Bedrock as the inference backend with per-user budgets, rate limits, and audit trails via LiteLLM.
Agentic Data Governance — the context ladder Learn to measure how governance context layers — data dictionaries, semantic metrics, and execution skills — improve data agent accuracy through a four-level ablation ladder on the BIRD benchmark.
Conclusion
June 2026 provides guidance and examples for operationalizing security at organizational scale; from maturity roadmaps and console access restrictions to AI agent registries and posture management platforms. The posts and samples provide patterns for DDoS visibility with flow logs, multi-tenant agent isolation with resource-based policies, egress controls for data exfiltration prevention, and governance frameworks for AI coding assistants. Each resource includes deployment steps or runnable code so you can validate in your own environment before adopting. Subscribe to the AWS Security Blog RSS feed to receive updates as they publish, and revisit this digest monthly for a consolidated view of what changed and what to act on.
If you have feedback about this post, submit comments in the Comments section below.
Security Hub is our foundation for full-stack enterprise security across clouds. It centralizes your security operations and turns raw signals into prioritized insights, so your team spends its time managing real risk instead of stitching tools together. Today that foundation grows in two directions our customers asked for most. We are adding purpose-built protection for AI workloads, and security monitoring for Microsoft Azure. Both are steps toward a bigger idea, that your best security tools should get smarter by working together.
These expansions came directly from customers, and they reflect where security is heading, not where it has been. The old promise of security tooling was a place to collect everything in one view. Collecting findings was never the hard part. The hard part is understanding them, connecting them, and acting before an attacker does, and doing it at the speed attacks now move. The programs that win from here will be the ones that see across their whole estate and respond fast, not the ones with the most dashboards. That is what we are building toward, and these launches are steps on that path.
Multicloud security management for Microsoft Azure
Customers across industries have made Security Hub a core part of how they run security on AWS. Most of them have run in more than one cloud for years, and they have been clear with us that they want Security Hub to also cover the rest of their estate. Today we do that for Microsoft Azure, with more clouds following quickly.
Security Hub now discovers Azure Virtual Machines, container images, Function Apps, and identities, then evaluates them for misconfigurations, internet exposure, and software vulnerabilities, with posture checks against the CIS Microsoft Azure Foundations Benchmark. Azure findings are prioritized next to your AWS findings using the same finding format, automation, and response workflows, so your team works from one understanding of risk across your entire estate. Azure resources are priced at the same rates as equivalent AWS resources with no additional fees, and there’s an independent 30-day free trial. To learn more, see the What’s New post.
This is not actually our first move beyond AWS. Earlier this year we introduced Security Hub Extended, bringing best-in-class partner solutions across nine security categories into the same experience you already use. Those partner solutions protect endpoints, identities, email, browsers, and data wherever they run, across any cloud, on-premises, and everywhere your enterprise operates. Extended was already our first multicloud and multi-workload step. Today we broaden what our own native capabilities cover, and the two lines of work now advance together.
Protecting AI workloads
Every customer I talk to is building with AI. Generative AI on Amazon Bedrock, model training on SageMaker, agents orchestrating workflows through AgentCore. These workloads are reaching production faster than most security programs can keep up, and teams often don’t yet have the tools to monitor model invocations, track agent behavior, or even know what AI assets exist across the organization. One security leader told me his team only caught a compromised service account, one that had been invoking a foundation model thousands of times, because finance questioned the bill. They found a security incident through an accounting review. The visibility gap is real, and it is already expensive.
This summer we start closing it with three launches. Two are GuardDuty capabilities for threat detection and investigation, and a third is a new Security Hub AI inventory.
GuardDuty AI Protection (generally available)
Amazon GuardDuty AI Protection delivers threat detection purpose-built for Bedrock and SageMaker. It detects anomalous model invocations, cost harvesting attacks where adversaries abuse stolen credentials to run inference at your expense, and prompt injection attempts through integration with Bedrock Guardrails.
Cost harvesting is accelerating. When credentials are compromised, attackers increasingly use them to invoke foundation models. Inference is expensive, demand is high, and stolen access converts straight to value without deploying any infrastructure. GuardDuty analyzes CloudTrail data events, learns what normal invocation looks like at scale, and flags the deviations that signal compromise or abuse. This is detection that only works at AWS scale, because you have to see the signal across millions of workloads to know what normal is. GuardDuty AI Protection is now available to all GuardDuty customers with a 30-day free trial.
GuardDuty AI-powered investigations (preview)
AI-powered investigations take on the manual investigation work that drives alert fatigue and slows response. The capability automatically analyzes GuardDuty findings and the accounts around them to separate true threats from benign activity.
It examines finding context, related activity from the last 90 days, affected resources, and threat indicators, using knowledge graphs and threat intelligence to complete in minutes what used to take hours. Each investigation returns a disposition assessment with confidence scoring, MITRE ATT&CK® classification, supporting evidence, and clear recommendations to suppress, contain, or remediate. Your team focuses on genuine threats, whether across a single account or an entire AWS Organization, and mean time to resolution drops. GuardDuty AI-powered investigations is available in preview in 10 AWS Regions.
Security Hub AI inventory (generally available)
You can’t secure what you don’t know exists. Security Hub now provides an AI inventory, a continuously updated, organization-wide view of your AI assets and their security posture. As teams deploy models, agents, and pipelines, security often can’t see what’s running, and without connecting those assets to active threats and misconfigurations, it’s difficult to know what to secure first.
Security Hub AI inventory discovers and catalogs AI workloads across your AWS environment two ways. For managed services, it inventories AWS Config resources across Bedrock, SageMaker, and AgentCore. For self-hosted and external workloads, it finds models running on EC2, ECS, and EKS through runtime analysis, and identifies the external model endpoints your workloads make calls to. It maps each asset to the infrastructure beneath it, including compute, networking, IAM roles, and data stores, and correlates it with security signals such as GuardDuty findings. So when GuardDuty AI Protection flags an anomalous invocation, AI inventory immediately shows you which infrastructure is involved, what’s connected to it, and where it belongs in your priority order.
AI assets multiply fast. A developer spins up a Bedrock agent for a proof of concept. A data science team stands up a SageMaker endpoint for internal testing. Another team wires in an external model API through a Lambda function. Multiply that across hundreds or thousands of accounts and you can quickly lose track. AI inventory gives you that view across every account in your organization, available in your Security Hub Essentials plan at no additional cost.
A different approach to full-stack security
These launches share something worth pausing on. You didn’t procure AI protection as a separate product, and you won’t stand up separate operations for Azure. You add them to the Security Hub you already run, and they show up in your prioritized view of risk. That same idea is what Security Hub Extended extends to the rest of the security estate.
Security Hub Extended now has 21 curated partners across nine categories: 7AI, Britive, CrowdStrike, Idira (CyberArk), Cyera, Island, LayerX, Native Security, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, SentinelOne, Splunk, Sublime, Upwind, Varonis, Zenity, and Zscaler. These are best-in-class solutions across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. None of them are here by default. Each one earned its place by committing to a shared view of where enterprise security is going, and by investing alongside us to build it. Curation is the point. A recommendation only means something if it can be turned down.
The commercial benefits of Extended are real today. Pay-as-you-go pricing, a single AWS bill, EDP eligibility, and no long-term commitments. But the work we’re most excited about goes further, and it’s not about procurement at all. Findings from every participating solution are emitted in the Open Cybersecurity Schema Framework (OCSF) and aggregated in Security Hub, and we’re building toward a single correlation across all of them, so a signal from an endpoint solution, an identity solution, and a cloud solution combine into one exposure and one attack path instead of three disconnected alerts. We’re working to reduce the deployment and onboarding effort between subscribing and seeing value. And we’re building the exchange that lets partner findings enrich each other, so the best-in-class tools you already trust become more than the sum of their parts. That is the differentiated future we’re investing in, and we’re building it in the open, guided by what customers ask for next. To learn more about Extended, see the What’s New post.
Accelerating forward
Step back and the shape of it is clear. Security Hub reaches across cloud providers, starting with Azure and expanding from there. It reaches across workload types with purpose-built AI protection and inventory. And it reaches across security categories through Extended and its curated partners. What began as a way to bring order to AWS security findings has become how more enterprises run full-stack security.
Detection and visibility are the foundation. What we build on top of them is a security experience that connects signals across every source you trust and helps you respond faster. It’s still Day 1, and Security Hub will keep extending as your environment, and the threats you face, continue to change.
If you have feedback about this post, submit comments in the Comments section below.
Amazon Web Services EMEA Sarl (AWS) has been designated as a critical third party (CTP) to the UK financial sector by HM Treasury.
The CTP regime came into force on January 1, 2025, and establishes a framework through which the Bank of England, PRA, and FCA (collectively the UK regulators) can set requirements on and have direct oversight of designated CTPs.
AWS supports the objectives of the UK regulators to ensure a robust financial system.
AWS obligations under the regime
The CTP regime is an outcomes-focused framework. Under the regime, AWS will be subject to requirements in relation to its designated Systemic Third-Party Services (STPS). The first step will be a self-assessment of these STPSs against the CTP regime criteria, which AWS will now carry out in line with regulators’ expected timelines.
AWS has actively engaged with the UK authorities as they’ve developed the CTP regime, and we will continue this constructive approach as we work to meet our obligations under it.
Impact on customers
The UK regulators have clarified that the requirements under the regime don’t eliminate, reduce, or replace the accountability of firms, their boards, and senior management for remaining operationally resilient, including when they rely on services provided by third parties.
The regime doesn’t change obligations on financial services customers of designated CTPs. As we manage our obligations, we expect to publish materials that customers can use to inform their own operational resilience planning and third-party risk management.
The AWS commitment to operational resilience
We’re focused on supporting financial services customers in enhancing their operational resilience and providing a range of services and guidance—including the AWS Well-Architected Framework and resources for cloud incident management—to help organizations deliver effective resilience outcomes.
AWS has a team of regulatory and technology experts with expertise in financial services ready to support customers with questions about this regime or operational resilience more broadly. Customers can contact their AWS account team for further information.
Amazon Web Services (AWS) is excited to release the Spring 2026 System and Organization Controls (SOC) 1 and 2 reports in machine-readable OSCAL format alongside the PDF version of the reports. The reports cover 188 services over the 12-month period from April 1, 2025 to March 31, 2026, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.
AWS is the first major cloud provider to offer key compliance reports to customers in the National Institute of Standards and Technology’s (NIST) Open Security Controls Assessment Language (OSCAL), as of June 2026. OSCAL is an open source, machine-readable (JSON) format for security information. The SOC 1 and SOC 2 report package in OSCAL format is now available as a distinct package in AWS Artifact, marking a milestone toward open, standards-based compliance automation. This machine-readable version of the SOC report package enables workflow automation to reduce manual processing time and modernize security and compliance processes. Your use cases for this content are innovative, and we want to hear about them through the contact information found in the OSCAL report package.
AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.
We’ve been thinking deeply about enterprise security. The operating model that served us for the past decade (collect telemetry, store it, query it, build dashboards to watch it) is no longer keeping pace. We need to shift to the new world: telemetry, context, reasoning, and actions. An approach that produces outcomes. The latest cybersecurity frontier models further made this shift urgent. Models like Claude Mythos can now find software vulnerabilities and reason through complex attack paths at machine-speed, leading to an exponentially increasing backlog of vulnerabilities.
Introducing AWS Continuum for code vulnerabilities
Today, we’re announcing AWS Continuum for code vulnerabilities, now available in gated preview. Continuum for code vulnerabilities addresses the full lifecycle of a code vulnerability at machine speed: from discovery through actions. It reasons over your environment, confirms what is real, and drives toward resolution. It’s model agnostic, using multiple frontier models where each performs best, and is built to incorporate the latest and most capable models as they emerge.
Continuum is built on lessons learned from running security across AWS and Amazon.com. Securing businesses that operate in different industries required a system that understands business context rather than applying generic rules uniformly.
How it works
Continuum for code vulnerabilities reasons over your full environment. This context includes structured data already living in Amazon Web Service (AWS) (your infrastructure, permissions, network topology, code) and the unstructured data that captures how your organization operates and your risk profile (your documents, communications, business priorities).
Continuum for code vulnerabilities operates in four continuous phases.
Discovery: Security teams tackle a backlog of vulnerabilities, and many are already using frontier models to find more. Continuum starts by ingesting that existing backlog and performing its own vulnerability scan of your environment. This creates a more comprehensive view of vulnerabilities and the associated attack paths.
Prioritization: Continuum uses context to evaluate, enrich, and prioritize every finding. Is the affected component deployed, is it reachable, is it in a production path, and what would the business impact be if exploited? The result is an evidence-backed list of priorities, allowing Continuum and your team to focus on what’s most important.
Validation: Continuum validates findings to surface false positives before they waste your team’s time. It contextualizes vulnerabilities against your environment. It then constructs working exploit examples in a sandboxed environment that provide concrete, reproducible evidence of the issue.
Mitigation and remediation: Continuum assesses existing defenses around a validated issue, including blocking and compensating controls along with detection mechanisms. It then draws on its understanding of the codebase, context, and findings to recommend mitigation or remediation of the vulnerability with a network change, policy change, or code patch. The patch recommendation is validated using the same system that confirmed the vulnerability. It also provides blast radius visibility and rollback paths where feasible.
This is just the beginning. We’re starting with code (1st and 3rd party) and then expanding to other aspects of security.
Trust is graduated
Continuum starts in learn mode with a human in the loop. Every recommendation includes the reasoning behind it. As you gain confidence, you can graduate Continuum to enforce mode, enabling remediation that can be increasingly automated based on categories and risk profiles you define.
Continuum capabilities
In addition to Continuum for code vulnerabilities, Continuum includes capabilities you might already know. The AWS Security Agent penetration testing and code scanning functionality is now part of Continuum as Continuum pen testing and Continuum code scanning (Preview). We’re also launching Continuum threat modeling in preview, which automatically generates comprehensive threat models from design documents or source code and outputs results in STRIDE format. These capabilities serve as detection and analysis sources that feed into the broader Continuum loop of discovery, prioritization, validation, and remediation.
Getting started
We’re working with customers across financial services, automotive, and technology to shape AWS Continuum. Customer feedback confirms the direction: security teams want tools that earn trust and take action.
AWS Continuum for code vulnerabilities is available in gated preview. Sign up to request access at AWS Continuum.
If you have feedback about this post, submit comments in the Comments section below.
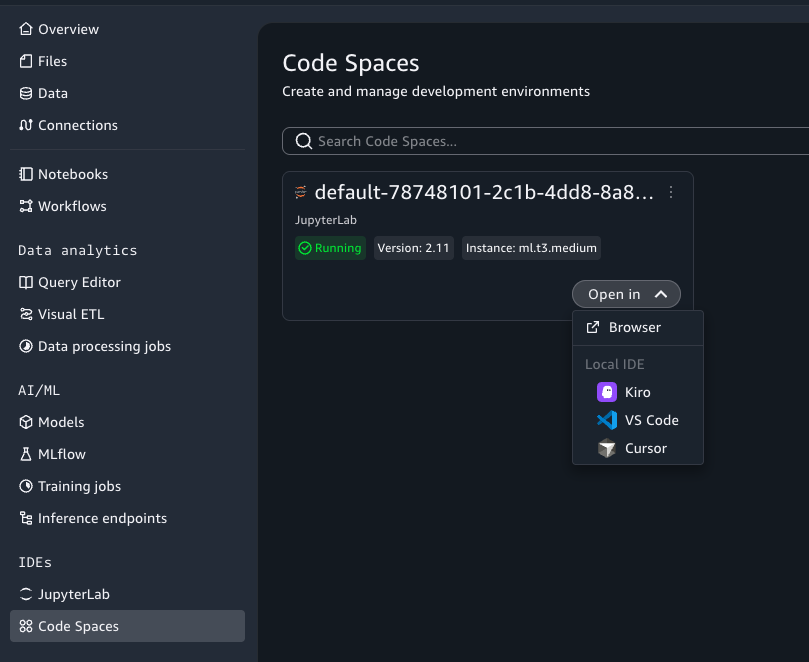
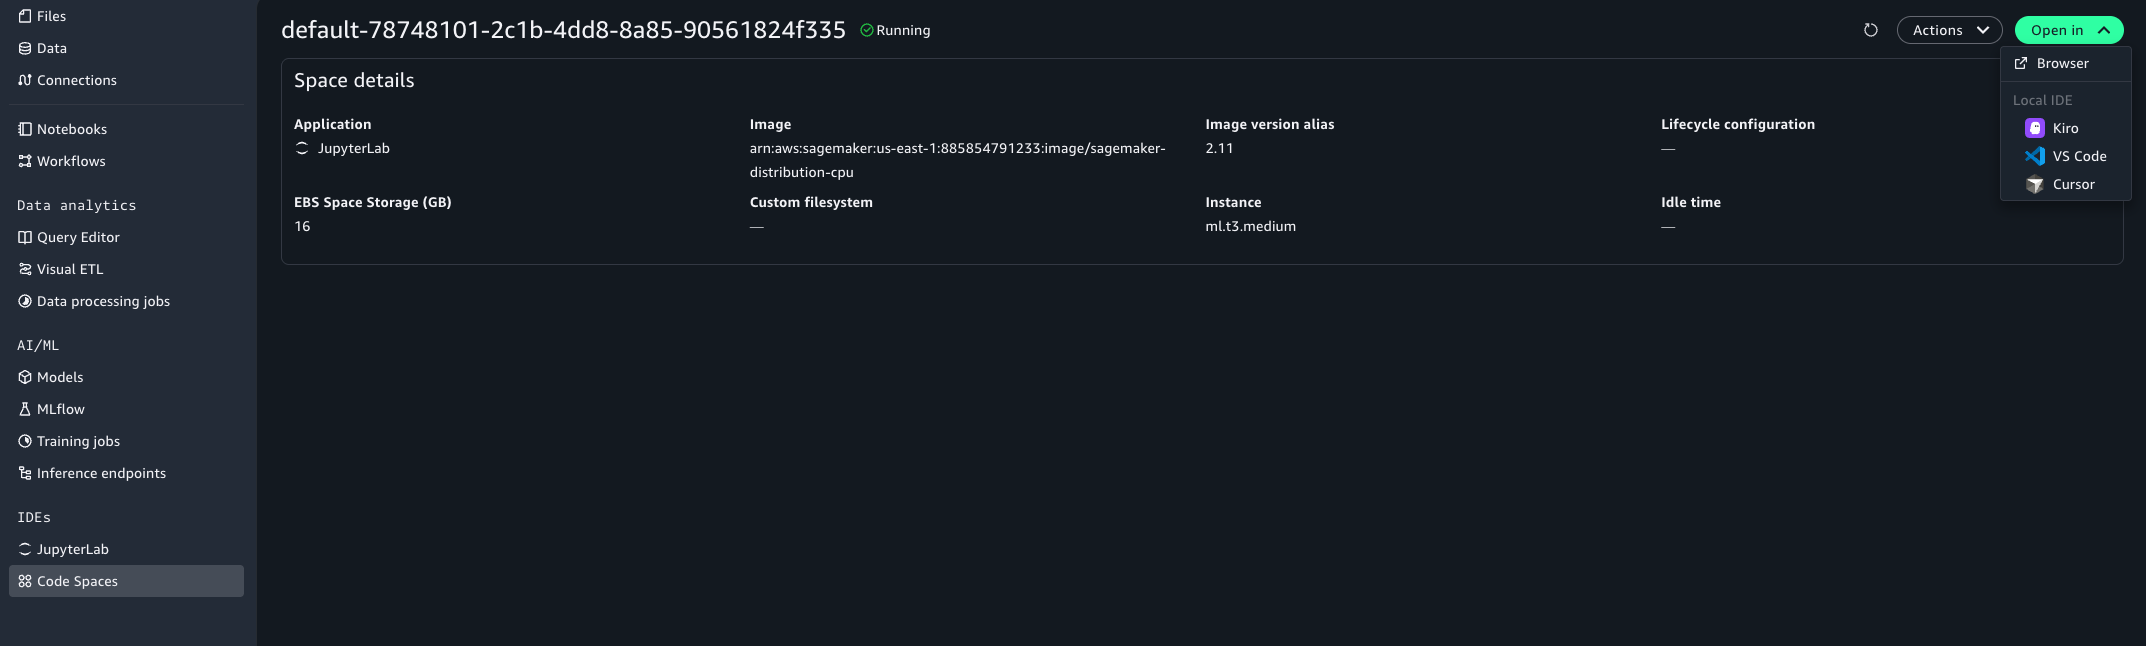
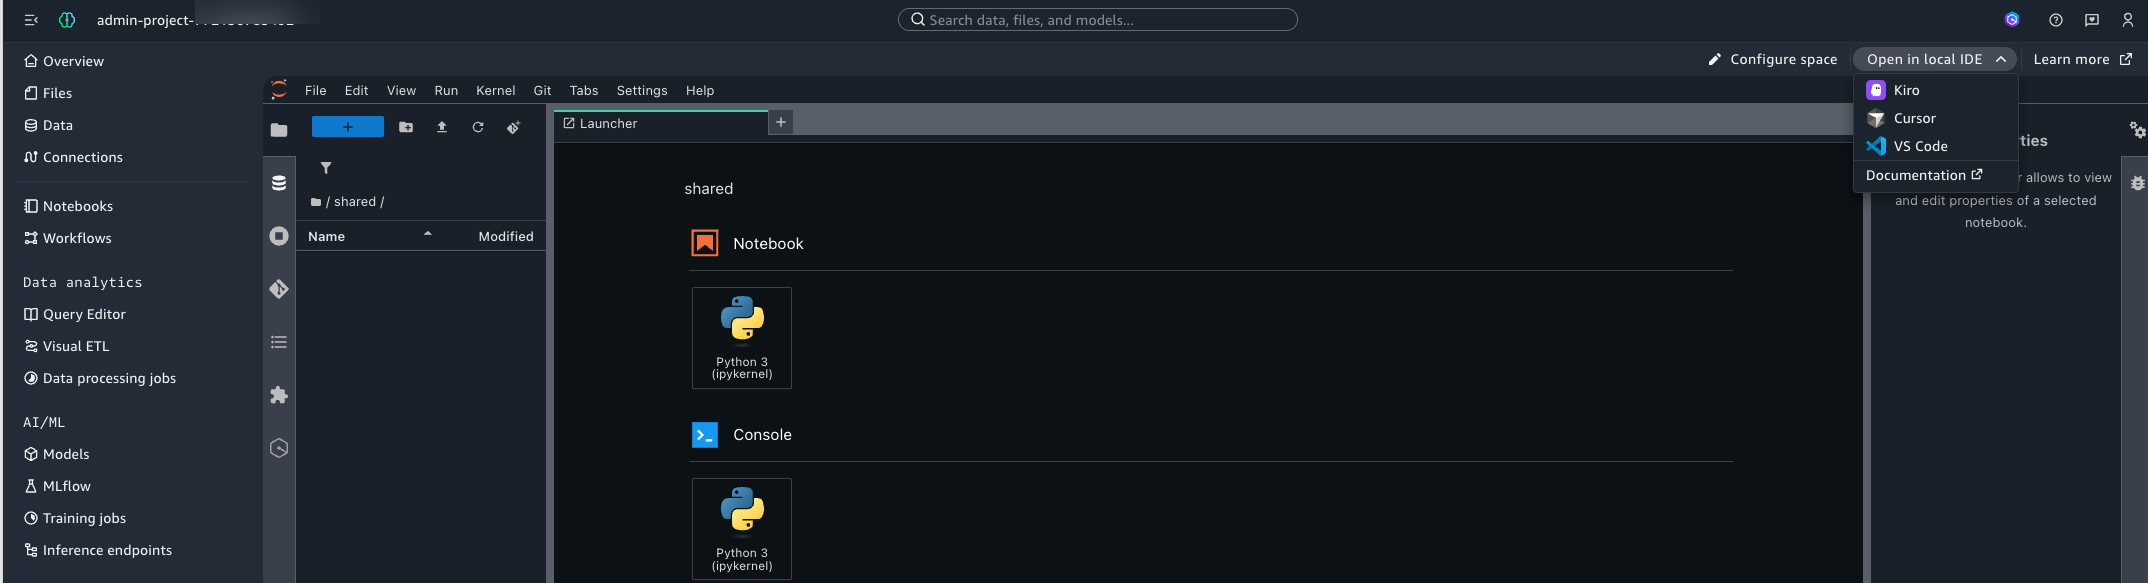
AI coding assistants are transforming software development, but data engineering presents unique challenges: governed data access, shared compute environments, and compliance controls that are designed to remain in place. How do you bring the power of agentic AI development into a governed data environment? With the AWS Toolkit for Visual Studio Code, you can connect Kiro, VS Code, or Cursor directly to Amazon SageMaker Unified Studio.
When you connect your editor to a SageMaker Unified Studio Space (a cloud-based compute environment inside your project), you get AI-assisted development with your preferred tools while your data governance, project permissions, and compute are managed by SageMaker Unified Studio. Additionally, SageMaker Unified Studio automatically generates steering files (like AGENTS.md) that provide your AI assistant with context about your project environment, so it understands your data and project configuration from the first prompt.
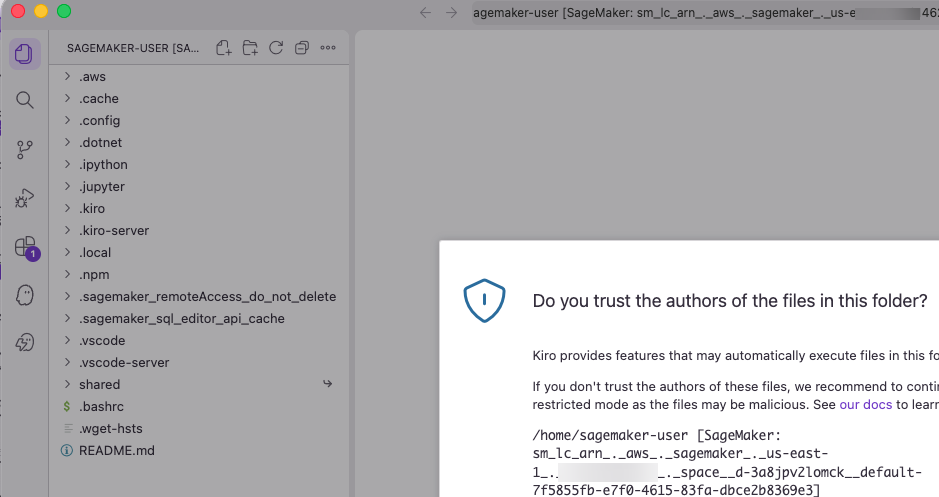
This post demonstrates the integration using Kiro. The same Remote Access connection works with VS Code and Cursor. The post starts by showing what you can do with this integration: using natural language to explore and analyze data in a governed environment. We then walk through the setup so you can try it yourself.
What’s new
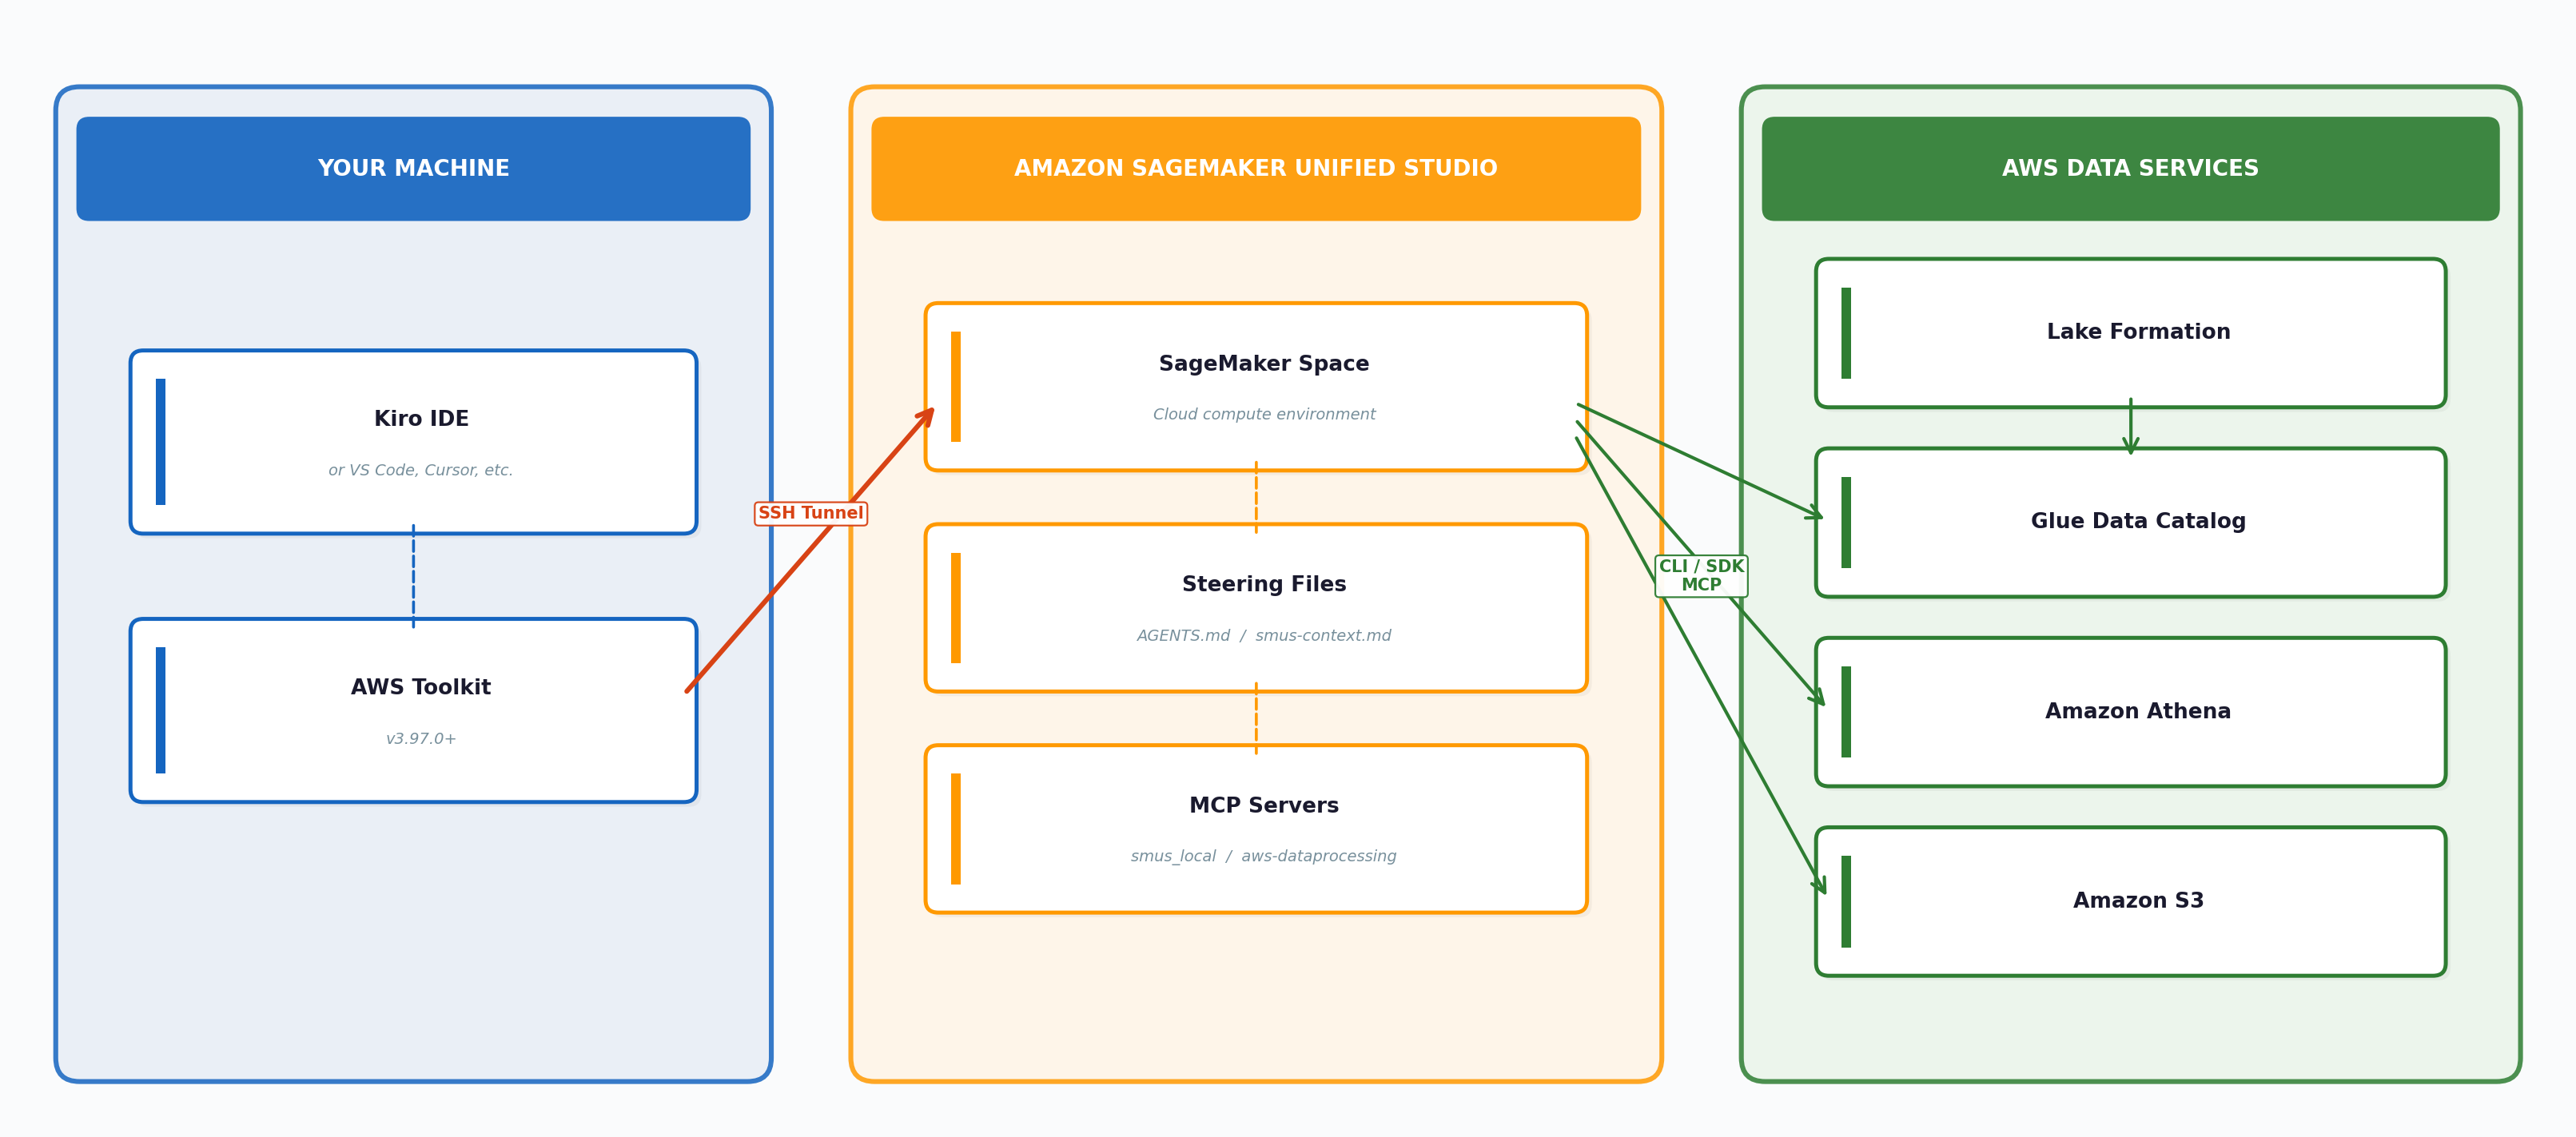
With the AWS Toolkit, you can connect Kiro, VS Code, and Cursor to your SageMaker Space over a secure SSH tunnel. No additional extensions or SSH key management required. After the connection is established, your IDE has full access to your Space’s file system, compute, and data services.
Two capabilities make this especially powerful for data work:
Automatic AI steering – When connecting Kiro to SageMaker Unified Studio, Kiro generates AGENTS.md and smus-context.md files that provide your AI assistant with context about your environment, including project configuration, environment details, and utilities for discovering your data catalog and project structure. Kiro detects these files automatically; other editors can use them as context for their own AI features.
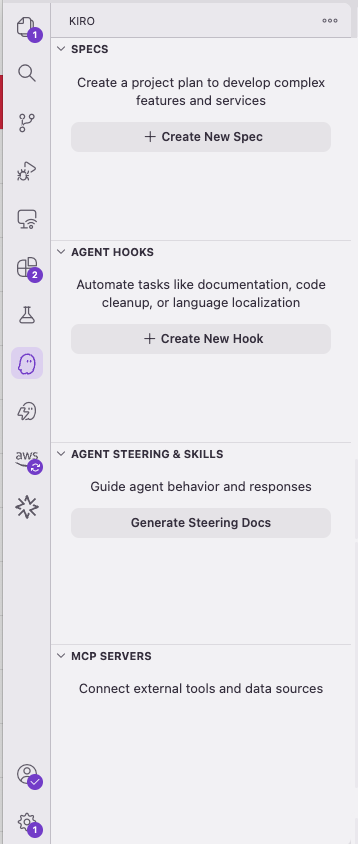
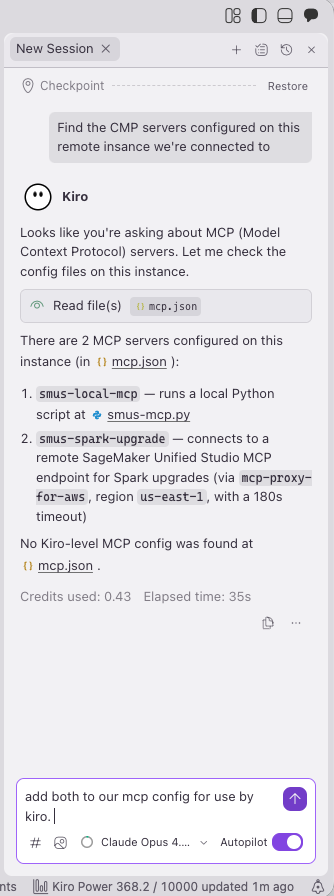
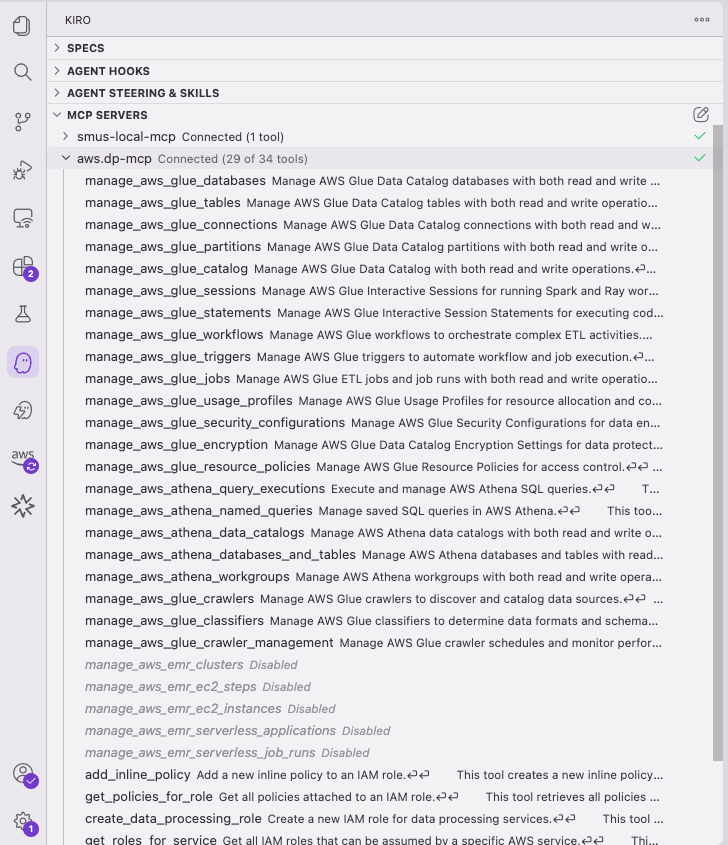
MCP server support – have Kiro discover and configure itself for the Model Context Protocol servers on your remote SageMaker space ( like smus_local and aws-dataprocessing) to give your agent direct access to your AWS Glue Data Catalog, Amazon Athena queries, and SageMaker Unified Studio project metadata.
The following diagram shows how the components connect:
Architecture diagram: How the components connect
See it in action: AI-assisted development with governed data
Before walking through the setup, we explain what you can do with this integration. This walkthrough uses Kiro as the editor. With Kiro connected to a SageMaker Unified Studio Space, MCP servers configured, and steering documents in place, we can use natural language to explore data and build analytics. The AI assistant has all the context it needs to do this well.
Note: Agentic AI output is nondeterministic. The exact code, tool choices, and responses Kiro produces will vary between sessions, even with the same prompt. The following walkthrough shows one representative session. Your experience will differ in the specifics, but the patterns and capabilities demonstrated here are consistent.
Step 1: Explore the data
Start with a simple prompt:
show my databases and the tables I have access to
Even with native MCP tools available, Kiro often prefers the AWS Command Line Interface (AWS CLI) and bash to retrieve information. This is expected and typically does not affect the outcome. If you prefer MCP tools for every operation, you can add that preference to a steering document.
Kiro used the sagemaker_studio SDK to discover the catalog:
python3 -c "
from sagemaker_studio import Project
project = Project()
conn = project.connection()
catalog = conn.catalog()
print('Databases:')
for db in catalog.databases:
    print(f'  - {db.name}')
"
Databases:
  - default
  - sagemaker_sample_db
Then it drilled into the table schema:
python3 -c "
from sagemaker_studio import Project
project = Project()
conn = project.connection()
catalog = conn.catalog()
db = catalog.database('sagemaker_sample_db')
print('Tables in sagemaker_sample_db:')
for t in db.tables:
    print(f'  - {t.name}')
    print(f'    Columns: {[(c.name, c.type) for c in t.columns]}')
"
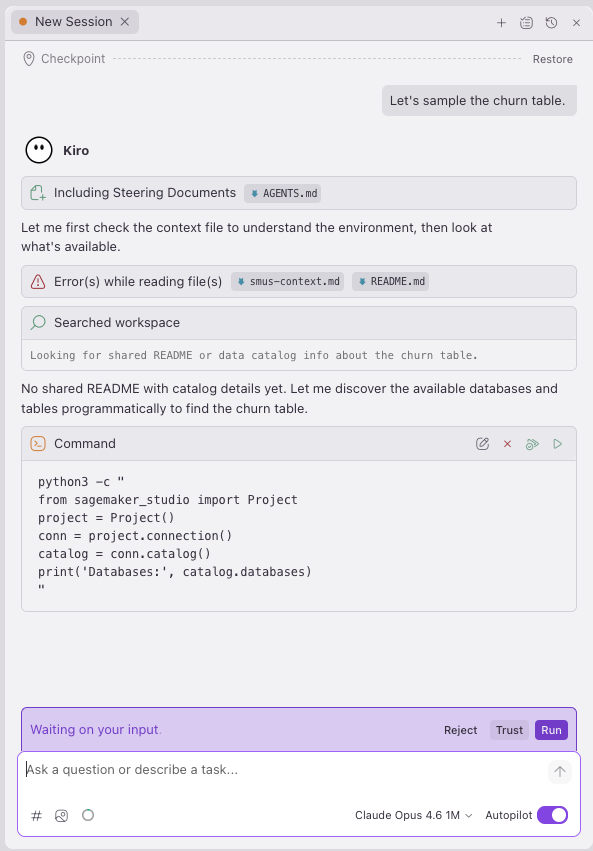
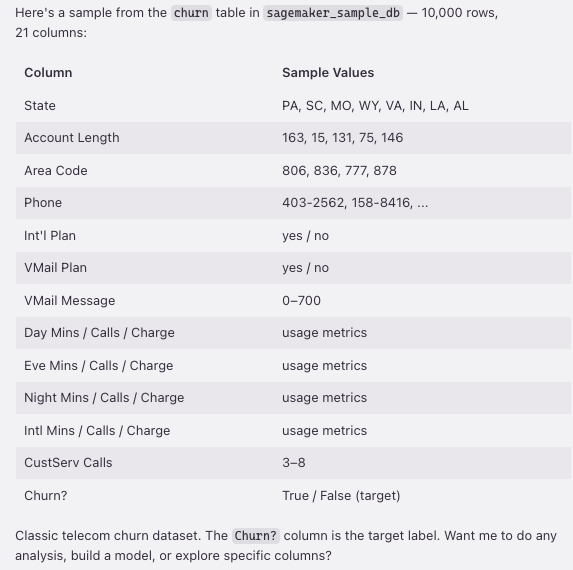
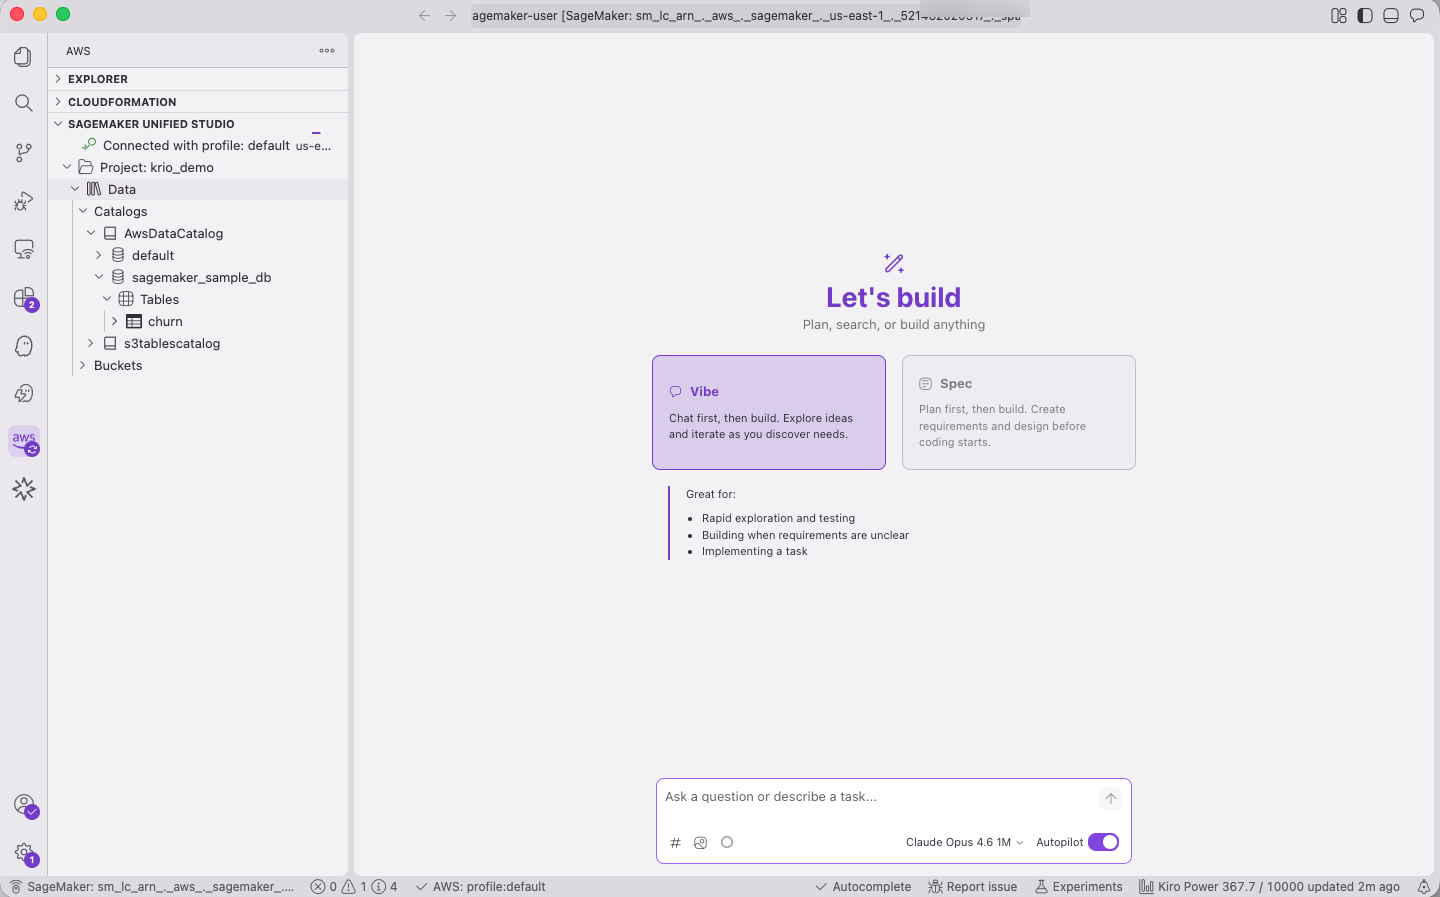
Kiro discovered the sagemaker_sample_db.churn dataset, a sample dataset that ships with SageMaker Unified Studio containing 10,000 rows and 21 columns of customer churn data (state, account length, call minutes, service calls, churn flag, and more). Notice that we did not write any of this code. We asked a question in natural language, and Kiro chose the right SDK calls, explored the catalog, and surfaced the results.
Another, more natural way to get the same answer is to ask directly. Prompting “Let us sample the churn table.” yields the same catalog paths and schema output, along with additional metrics like row count and a data sample, all from a single conversational prompt:
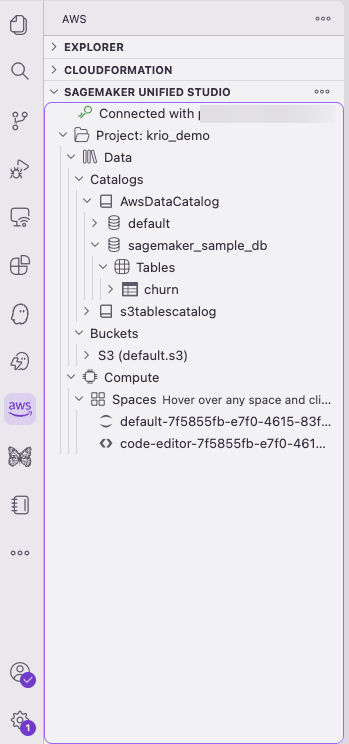
Figure 1 — The sagemaker_sample_db.churn dataset in the catalog
Figure 2 — Churn dataset schema with 21 columns
from sagemaker_studio import sqlutils
result = sqlutils.sql(
    'SELECT COUNT(*) AS total_rows FROM sagemaker_sample_db.churn',
    connection_name='default.sql'
)
print('=== Total Row Count ===')
print(result)
=== Total Row Count ===
   total_rows
0       10000
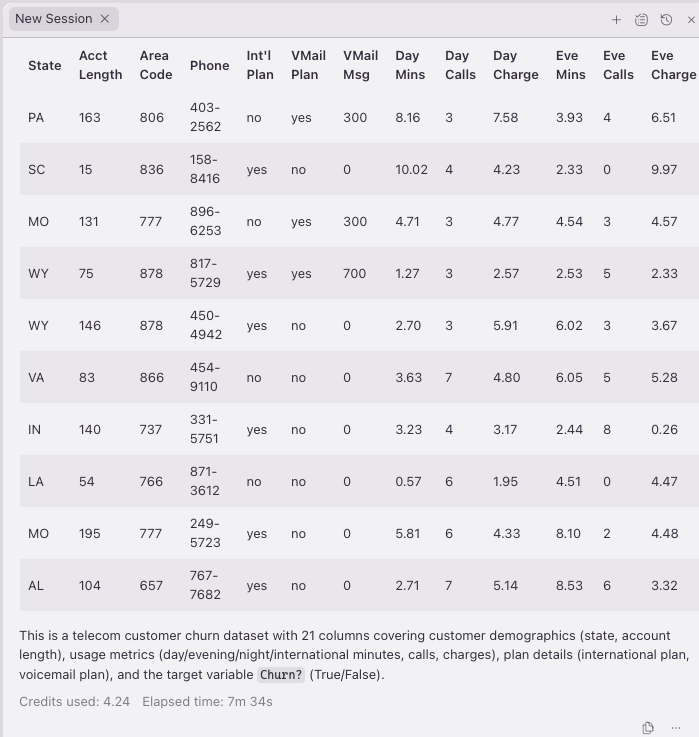
With the schema and row count in hand, Kiro sampled the data to round out its understanding of the dataset:
Figure 3 — Comprehensive data sample after Kiro catalog exploration
Step 2: Run analytics with full context
With the data explored, ask Kiro to run a data quality evaluation:
Can we run basic statistical evaluations for data quality?
Because Kiro had already explored the catalog and sampled the data, it made smart choices about how to run the analysis. Instead of using PySpark for this 10,000-row table, Kiro used Athena using sqlutils to run the evaluation directly. It produced a thorough data quality report:
10,000 rows, 21 columns, zero nulls across all columns. Clean on that front.
5,000 duplicate rows (50 percent). Significant, worth investigating before modeling.
Outliers minimal. Most columns have less than 1 percent outlier rate by IQR.
Clear signal in key features. Churners and non-churners show differences in day_mins (7.52 vs. 3.52), eve_mins (5.95 vs. 4.11), and vmail_message (175 vs. 278).
State distribution roughly uniform (~2% each), intl_plan and vmail_plan near 50/50.
The key insight here is what Kiro did not do. It did not default to PySpark because the environment supports Spark. Having explored the data first, understanding the table size, column types, and that churn is a proper Boolean (not a string), Kiro independently chose the right engine for the workload and produced correct analytics on the first pass.
Best practice: Explore first, code second
Start every AI-assisted development session with data exploration. Ask your AI assistant to discover your catalog, sample your tables, and understand the schema before asking it to build anything. This single step helps reduce a common source of errors in AI-assisted data work: the LLM making assumptions about data it has not seen.
Exploring your data gives the large language model (LLM) the context it needs to properly help with your project. It saves hallucinations and rework, results in faster development time, and reduces token costs.
Ready to try it yourself? The following sections walk through the full setup: prerequisites, connecting your editor to your SageMaker Space, configuring MCP servers, and working with notebooks.
Prerequisites
Before you begin, make sure you have the following:
A SageMaker Unified Studio domain and project with at least one project that has a compute environment provisioned (Tooling or ToolingLight). These should come standard with every SageMaker project except those provisioned with the SQL & Gen AI blueprints. If you need to set up SageMaker Unified Studio, see Getting started with Amazon SageMaker Unified Studio.
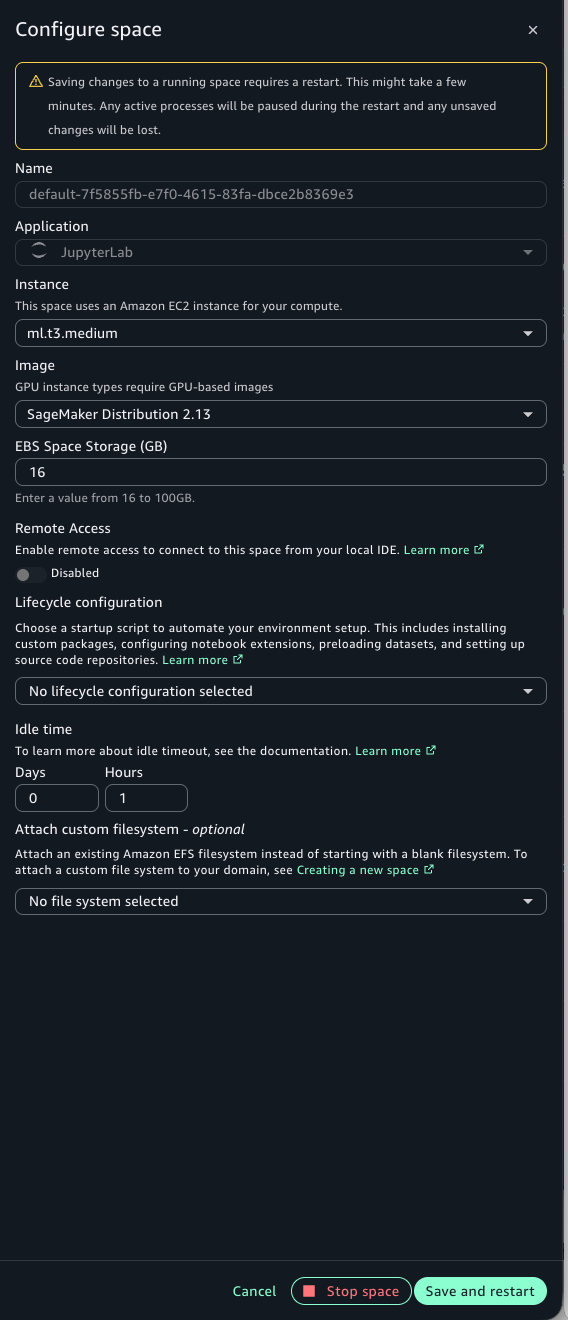
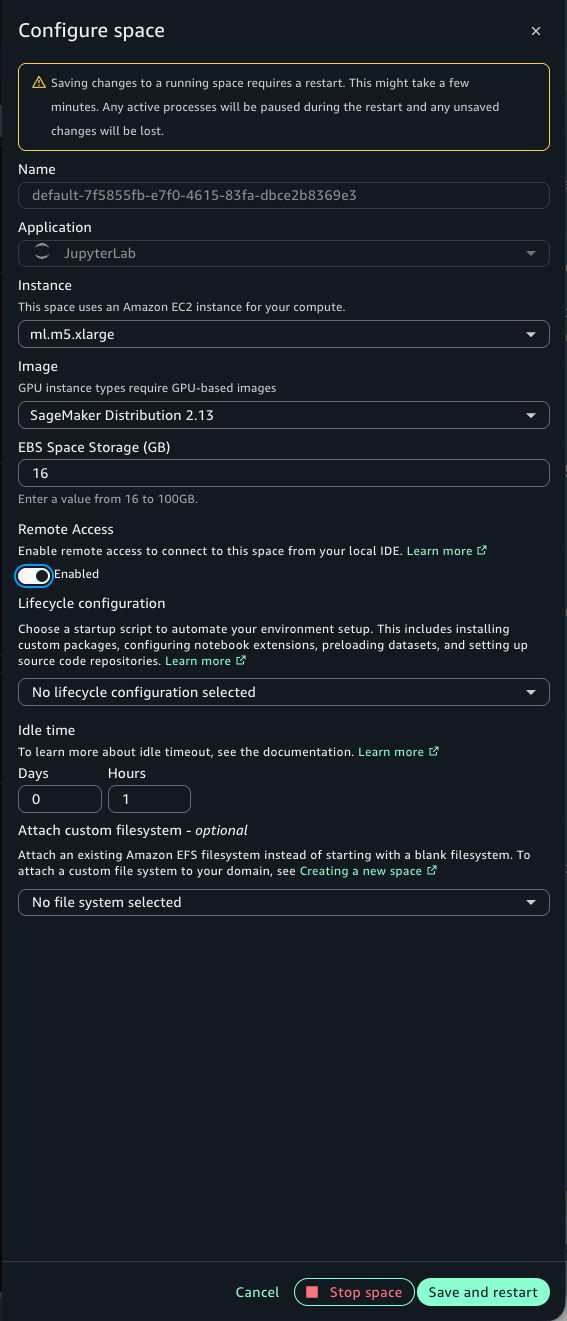
A Space with Remote Access enabled. Either a JupyterLab or Code Editor Space works. The instance must have at least 8 GiB of memory (for example, ml.t3.large or larger). The default ml.t3.medium (4 GiB) can’t enable Remote Access. You must upgrade the instance type first, then toggle Remote Access to Enabled in the Configure Space dialog.
A VS Code-compatible editor. Kiro, VS Code, Cursor, or another VS Code-based IDE installed on your local machine. This walkthrough uses Kiro, but the Remote Access connection has been tested with VS Code and Cursor as well.
AWS Toolkit v4.1.0 or later. Kiro ships with the AWS Toolkit pre-installed. For VS Code and Cursor, install the AWS Toolkit extension and verify your version is 4.1.0 or later (Cmd+Shift+X and search for “AWS Toolkit”).
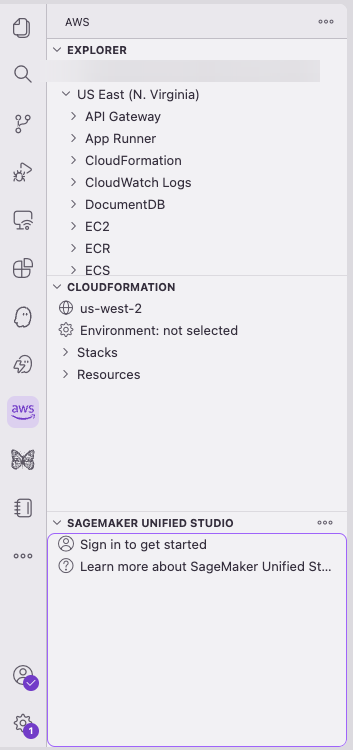
AWS credentials. You must be authenticated in the SageMaker Unified Studio panel of the AWS Toolkit with the same identity (AWS IAM Identity Center or AWS Identity and Access Management (IAM)) that you use to access SageMaker Unified Studio in the browser.
Network connectivity. Your Space must have internet access (PublicInternetOnly mode, or virtual private cloud (VPC) with a NAT gateway or HTTP proxy that allows VS Code and Open VSX endpoints).
The following screenshots show the SageMaker Unified Studio portal and the Configure Space dialog. Navigate to your project, select your Space, and verify the configuration. Remote Access is disabled when the instance has less than 8 GiB of memory. Select an instance with at least 8 GiB, such as ml.t3.large, then enable Remote Access. This is a one-time configuration per Space.
Figure 4 — SMUS project Spaces overview in the portal
Figure 5 — Configure Space dialog showing instance type selection
Figure 6 — Enabling Remote Access on a Space with 8 GiB or more
Connecting your editor to your SageMaker Space
There are two ways to connect: directly from the SageMaker Unified Studio portal, or from your local IDE using the AWS Toolkit.
Method 1: Connect from the SageMaker Unified Studio portal
To launch your IDE directly from the portal, navigate to your project’s Code Spaces page, find your Space, and choose Open in to select your editor (Kiro, VS Code, or Cursor):
Figure 7 — Open in Local IDE from the Code Spaces list
You can also launch from within a Space’s details page:
Figure 8 — Open in Local IDE from the Space details page
Or from within the JupyterLab or Code Editor browser environment:
Figure 9 — Open in Local IDE from JupyterLab
Your browser will prompt you to allow opening the IDE. Confirm, and the editor launches with an SSH connection to your Space already established via the AWS Toolkit. No additional configuration is typically required.
Method 2: Connect from your IDE via the AWS Toolkit
Open your editor on your local machine. Then, in the AWS Toolkit panel, choose Sign in. Authenticate with your IAM Identity Center or IAM credentials, the same identity you use to access SageMaker Unified Studio in the browser. The following screenshots show Kiro, but the steps are the same in VS Code and Cursor. Figure 10 — AWS Toolkit button in Kiro
Figure 11 — AWS Toolkit panel expanded
Figure 12 — AWS Toolkit Sign in dialog
Choose your AWS profile. You must have a profile configured in the AWS CLI with the correct account and AWS Region set.
In the Toolkit panel, browse your SageMaker Unified Studio domains and projects. Select the project that you want to work in.
Figure 13 — Browsing SMUS domains and projects in Kiro
Important: The credentials that you use in the AWS Toolkit must match the identity that you use in the SageMaker Unified Studio portal. The Toolkit validates that your identity has access to the Space.
AI steering: How SageMaker Unified Studio pre-seeds AI context
The real value of the feature comes from what you don’t need to do. When connected to Kiro SageMaker Unified Studio automatically generates steering files that guide your AI assistant with project context, so you can focus on building analytics rather than configuring connections. When you open a SageMaker Unified Studio project, SageMaker Unified Studio presents a prompt to create steering files: an AGENTS.md file that references a newly created smus-context.md. These files provide context about your project environment, such as project configuration, environment details, and utilities for discovering your data catalog and project structure. Kiro detects and applies these files automatically; in other editors, you can reference them as context for your AI features.
Figure 14 — SMUS popup offering to create steering files
Figure 15 — Generated AGENTS.md and smus-context.md steering files
Without these steering files, your AI assistant would need several back-and-forth prompts to discover what data you have and how to access it. With them, the assistant understands your project from the first prompt: how to discover your databases, how your environment is configured, and what tools are available. The steering files also help properly configure MCP servers, which you set up in the next section.
Exploring your project
After you’re connected, the project structure expands into Data and Compute sections in the sidebar, as it would in the SageMaker Unified Studio portal.
Figure 16 — Project Data and Compute sections in the Kiro sidebar
You can explore your data catalog and S3 buckets directly from the sidebar:
Figure 17 — Exploring the data catalog and S3 buckets from the sidebar
You can also remote into a compatible Space for direct development. Hover over a Space and select the remote icon on the right:
Figure 18 — Remote connection icon on a compatible Space
After a moment, the Space opens in a new Kiro window:
Figure 19 — Space opened in a new Kiro window
You must sign in again, and then trust the authors of the files in the Space:
Figure 20 — Trust authors dialog for the Space files
You’re now connected to your Space. The Toolkit works on the Space the way it does locally, except the resources are scoped to the project’s permissions.
Figure 21 — Connected to the SMUS Space with the Toolkit active
Setting up MCP servers
Before you can use AI-assisted development effectively, you must give Kiro access to your data services through Model Context Protocol (MCP) servers. MCP servers extend the Kiro agent with tools: the ability to query catalogs, run SQL, manage credentials, and more.
Out of the box, Kiro has no MCP servers configured:
Figure 22 — Kiro MCP servers panel with no servers configured
Prompt Kiro to find and configure the MCP servers that ship pre-installed on your SageMaker Space. Using the steering file context, Kiro located the servers and generated the configuration. If a server fails to connect, select the failed entry and Kiro will suggest fixes. You might need additional prompts to get the smus_spark_upgrade server (a pre-installed MCP server for managing Spark session upgrades) working correctly.
Figure 23 — Kiro discovering and configuring SMUS MCP servers
Figure 24 — MCP servers after iterating on configuration fixes
For more deterministic results, you can also configure the MCP servers manually. Here is a sample configuration:
Note: Your MCP configuration might vary depending on your SageMaker Unified Studio environment. Use the preceding configuration as a starting point and let your editor adjust if a server fails to connect.
Next, add the AWS Data Processing MCP server to get catalog information and Athena query capabilities. This isn’t strictly required (Kiro can use Python or AWS CLI for the same tasks), but it gives the agent native tools for catalog and query operations.
Figure 25 — AWS Data Processing MCP server tools with Amazon EMR tools disabled
You can list the tools that each MCP server provides. Because the AWS Data Processing MCP server includes tools for many services, we recommend disabling tools that you don’t need for a given project to save model context. For this walkthrough, disable the Amazon EMR tools to focus on AWS Glue and Amazon Athena.
Exploring data with notebooks
Kiro supports Jupyter notebooks in your SageMaker Space with the same language and connection selectors that you would find in SageMaker JupyterLab or Code Editor. Open the command palette (Cmd+Shift+P) and create a new Jupyter notebook:
Figure 26 — Command palette to create a new Jupyter notebook
Figure 27 — New Jupyter notebook opened in Kiro with language and connection selectors in a notebook cell
As in SageMaker JupyterLab, you get language and connection selectors in the bottom right of each cell. Choose the connection selector to see your available connections:
Figure 28 — SageMaker connection selector
Select PySpark to fill in the magic commands for your cell. Write your code (in this case, enter spark and press Shift+Enter) to verify the session starts:
Figure 29 — PySpark magic command and spark verification code
Figure 30 — Running the PySpark cell
If this is your first time using Jupyter with Kiro, you’re prompted to install the Jupyter extension. After it’s installed, select the kernel from Python Environments → Base:
Figure 31 — Jupyter kernel selection prompt
Figure 32 — Selecting the Python kernel from the Base environment
Re-run your cell. After a few moments, AWS Glue provisions a PySpark session:
Figure 33 — AWS Glue provisioning a PySpark session in a Jupyter notebook in Kiro
You see results the way you would in JupyterLab in the SageMaker Unified Studio portal:
Figure 34 — PySpark code running in a Jupyter notebook in Kiro
The notebook generate button
You will notice a Generate button underneath notebook cells. Let’s test it with a simple prompt:
looking at the above cell for reference, show me the accounts where state = california
using pyspark prefixing the cell with `%%pyspark default.spark` and sorting by
account_length
Figure 35 — Using the Generate button with a natural language prompt
Figure 36 — Generated PySpark code from the prompt
This prompt builder, like other notebook generation features, doesn’t have good context on the surrounding cells. You must be explicit about what you want because it won’t read other code or cells as input.
While the Kiro notebook generate button works for straightforward edits, for serious code generation, we recommend that you use Kiro agent mode. This mode has full project and SageMaker context, as demonstrated in the “See it in action” walkthrough earlier in this post.
What’s happening under the hood
When you connect your editor to a SageMaker Unified Studio Space, the AWS Toolkit extension establishes a secure SSH tunnel between your local IDE and your cloud-based Space.
Key details:
SSH tunnel. The connection is managed entirely by the AWS Toolkit (v4.1.0+) or VS Code’s built-in SSH extension. No separate Remote SSH extension is needed; the capability is built in.
File system access. Your editor sees the Space’s persistent storage at /home/sagemaker-user/, including shared project files and notebooks or scripts you create.
SageMaker Unified Studio steering context. The integration generates AGENTS.md and smus-context.md files that provide your AI assistant with context about your project environment and utilities for understanding your data. This is what makes the assistant effective from the first prompt.
MCP server integration. MCP servers like smus_local (for project metadata and environment utilities) and aws-dataprocessing (for AWS Glue Data Catalog and Amazon Athena) extend your editor’s AI with direct access to your data services. Your own MCP servers will be equally valuable here.
Credential flow. The Toolkit uses your existing AWS identity (IAM Identity Center or IAM) to authenticate to the Space. No separate SSH keys to manage. The aws_context_provider tool from the smus_local MCP server handles credential discovery for agent operations.
Best practices
To work effectively with your IDE and SageMaker Unified Studio:
Explore your data before building. Start every session by asking your AI assistant to discover your catalog, sample your data, and understand the schema. This single step helps reduce the most common source of errors in AI-assisted data work: the LLM making assumptions about data it has not seen. See the “See it in action” walkthrough earlier in this post for a concrete example of the difference this makes.
Use the SageMaker Unified Studio steering files. When prompted to create AGENTS.md and smus-context.md, accept. These files are the foundation that makes everything else work: environment context, MCP server configuration, and project understanding. Without them, your AI assistant starts from zero on every prompt. Kiro detects these automatically; in other editors, add them as context.
Disable unused MCP tools. The AWS Data Processing MCP server includes tools for AWS Glue, Amazon EMR, Amazon Athena, and more. Disable the services that you’re not using for a given project to save model context and reduce noise.
Be specific in your prompts. The more detail you give your AI (column names, query patterns you prefer, output formats), the closer the first pass will be. “Run data quality evaluation using Athena SQL” gets you better code than “check my data.”
Always test interactively first. Whether in notebooks or the terminal, validate code before deploying it. AI agents can iterate quickly, but catching issues in an interactive session is faster than debugging a failed AWS Glue job. Athena PySpark and the SageMaker sqlutils and sparkutils packages are great for this.
Stop your Space when idle. Your Space runs on compute (the same instance types as Code Editor and JupyterLab). If idle, the Space will terminate after 60 minutes and close your remote connection. Close the remote window and reconnect to continue.
Things to know
Notebook agent mode. For notebook-heavy analytics workflows where you want agentic AI to generate and run cells directly, SageMaker Notebooks with Data Agent in SageMaker Unified Studio is the recommended option today. Current notebook support in local editors covers editing, running, and generating code in individual cells.
MCP setup takes iteration. Configuring MCP servers may require iteration, especially for servers with complex authentication. Many AI-enabled editors can self-correct when a server fails. For more deterministic results, use the preceding MCP configuration JSON as a starting point rather than relying solely on auto-discovery.
CLI preference. AI agents often prefer the AWS CLI and bash even when MCP tools are available. This doesn’t affect outcomes, but you can steer your assistant toward MCP tools using a steering document if you prefer consistency.
Security and governance boundaries
A core benefit of this integration is that your existing security and governance controls remain enforced. Your editor connects to your SageMaker Space through a secure SSH tunnel managed by the AWS Toolkit. It does not bypass your organization’s access controls. Data access is governed by the same AWS Lake Formation permissions and IAM Identity Center authentication that apply when you work in the SageMaker Unified Studio portal directly. Your project-level permissions, database grants, and column-level security policies apply consistently whether a query originates from an AI agent, a notebook cell, or the SageMaker console. Data access is governed by the boundaries you define in your SageMaker Unified Studio domain and project configuration.
Clean up
To avoid ongoing charges from billable resources (SageMaker Space compute charges per hour, AWS Glue sessions charge per DPU-hour, Amazon Athena queries charge per TB scanned):
Stop your Space – In the SageMaker Unified Studio portal, navigate to your project’s Spaces and stop the Space you used for this walkthrough.
Disconnect: Close the remote connection in your editor (File → Close Remote Connection).
Verify AWS Glue sessions are terminated – If you ran PySpark queries during this walkthrough, verify that the sessions are stopped. In the SageMaker Unified Studio portal, navigate to Data processing and confirm no active AWS Glue sessions remain. Sessions auto-terminate when the Space stops, but verify to avoid unexpected charges.
Delete demo resources (optional) – File deletion is permanent and cannot be undone. Back up any work that you want to retain before proceeding. If you created scripts or files during this walkthrough that you no longer need, delete them from /home/sagemaker-user/. For example, delete any test notebooks, Python scripts, or generated data files. The sample sagemaker_sample_db.churn dataset is read-only and doesn’t need cleanup.
Conclusion
This post showed what happens when agentic AI meets governed data, and walked through how to set it up yourself.
Three key insights emerged from this hands-on experience:
SageMaker Unified Studio steering files transform the developer experience. Your AI assistant is project-aware from the first prompt, understanding your environment and available data without manual setup.
MCP servers bridge “AI that writes code” with “AI that queries your data”. The smus_local and aws-dataprocessing servers are essential for effective agentic data work.
The “explore first” pattern pays immediate dividends. When your AI assistant understands your data before writing code, it makes smarter engine choices and produces correct analytics on the first pass.
This integration brings together two capabilities that are stronger together: your IDE handles the AI-assisted coding and iteration, while SageMaker Unified Studio handles data governance, access control, and compute management. You get the productivity of an agentic AI coding assistant without compromising on the controls your organization requires.
Running Snowflake on AWS means navigating two distinct sets of best practices simultaneously: AWS Well-Architected guidance for infrastructure, and Snowflake Well-Architected Framework guidance for compute, data organization, and governance. Without a unified review framework, security controls go unmapped to Snowflake configurations. Production readiness timelines stretch as teams reconcile guidance from two separate review processes, and compliance posture becomes difficult to demonstrate when audit evidence spans disconnected sources. The Snowflake and AWS Custom Well-Architected Framework Lens closes that gap.
The lens brings together AWS Well-Architected best practices and Snowflake guidance into a single review experience, with integrated recommendations that reflect how the two services compose in production. It evaluates your architecture across the seven AWS Well-Architected pillars: security, reliability, performance efficiency, cost optimization, operational excellence, and sustainability. A single review surfaces findings like misconfigured Snowflake network policies alongside Amazon Virtual Private Cloud (Amazon VPC) controls, or cost inefficiencies that span both Snowflake virtual warehouse sizing and Amazon Elastic Compute Cloud (Amazon EC2) instance selection. In this post, we walk through each pillar, the three access points (AWS Management Console, Kiro, and Snowflake Cortex Code), and how to run your first review.
What’s in the lens?
The Snowflake and AWS Custom WAF Lens defines seven pillars for joint Snowflake-on-AWS architectures, drawing from both the seven-pillar AWS Well-Architected Framework and the five-pillar Snowflake Well-Architected Framework.
Pillar 1: Security and identity
Security for Snowflake on AWS requires coordinated identity and access controls across two distinct planes. On the AWS infrastructure side, services like AWS Key Management Service (AWS KMS), AWS IAM Identity Center, and Amazon VPC configurations govern access and encryption. On the Snowflake side, network policies, role-based access control (RBAC) hierarchies, and OAuth or key pair authentication control who can access data. The following table maps the most critical security domains (identity, network, authentication, and authorization) across both services, with integrated recommendations for where the two layers must align to help prevent unauthorized access.
Domain
AWS guidance
Snowflake guidance
Integrated recommendation
Network security
Amazon VPC design, AWS PrivateLink endpoints, AWS service endpoints, Amazon EC2 security groups
Network policies, IP allow lists
Use AWS PrivateLink between Amazon VPC and Snowflake; layer Snowflake network policies on top of EC2 security groups for defense-in-depth
Identity and access
AWS Identity and Access Management (IAM) roles, federation, least privilege
Database roles, role hierarchy, MFA
Federate Snowflake authentication through AWS IAM Identity Center; map identity provider groups to Snowflake database roles for consistent RBAC
Authentication
MFA for human IAM users; integrate with corporate IdP via IAM Identity Center
RSA key pair for service accounts; SAML SSO or OAuth for humans; disable-password only
Store private keys in AWS Secrets Manager; rotate via automation; unified IdP for both systems via SAML federation
Authorization
Service control policies at organization level as hard guardrails; permission boundaries on delegated roles
Role hierarchy with inheritance; SECURITYADMIN for grants separate for SYSADMIN
Protecting data itself, independent of who accesses it, spans two complementary layers. On the AWS infrastructure side, services like AWS KMS, AWS IAM Identity Center, and Amazon Simple Storage Service (Amazon S3) lifecycle policies govern encryption, classification, and retention of data at rest. On the Snowflake side, dynamic data masking, row access policies, Tri-Secret Secure, and automatic classification protect sensitive data at the query layer. The following table maps the most critical governance domains (classification, dynamic data masking, lineage, retention, and compliance) across both systems, with integrated recommendations for maintaining consistent data protection end-to-end.
Use AWS KMS with Snowflake Tri-Secret Secure for dual-custody encryption; apply Snowflake masking policies for column-level protection
Audit and compliance
AWS CloudTrail, AWS Config, AWS Security Hub
Event tables, Account Usage, Access History, Sensitive data classification
Stream Snowflake audit logs to Amazon CloudWatch or Amazon OpenSearch Service using Amazon S3 and Amazon EventBridge for consolidated compliance monitoring. AWS provides compliance-enabling capabilities; your team uses them to support and demonstrate compliance.
Row access policies
AWS Lake Formation row-level filters, Amazon S3 Access Points for team-scoped access
Row access policies for multi-tenant isolation or regional data residency; role-based row visibility
Define row-level security once in Snowflake (single enforcement point); restrict AWS-side to pipeline service account
Pillar 3: Reliability
Reliability in a Snowflake on AWS architecture depends on how well the two systems coordinate during failure scenarios, from AWS infrastructure disruptions to Snowflake service availability events. The following table covers the key reliability domains, including cross-Region replication, failover configuration, and workload isolation, with integrated guidance for building a resilient architecture across both systems.
Align Snowflake Time Travel retention with Amazon S3 versioning policies; use zero-copy clones for pre-deployment testing without storage overhead
Recovery objectives
RTO and RPO planning, backup strategies
Replication lag monitoring, failover SLAs
Define joint RTO and RPO targets that account for both Snowflake replication lag and AWS infrastructure recovery time
Pillar 4: Performance optimization
Performance efficiency for Snowflake on AWS requires tuning at both the infrastructure and application levels. AWS instance selection, network throughput, and storage configuration directly affect how Snowflake warehouses perform. Snowflake-specific patterns like warehouse sizing, query optimization, and clustering keys determine how efficiently compute is used. The following table covers the primary performance domains with integrated recommendations for both layers.
Right-size Snowflake warehouses based on query profiling; use multi-cluster warehouses for concurrency scaling aligned with application tier automatic scaling
Optimize Amazon S3 staging file sizes for Snowpipe ingestion; apply clustering keys on frequently filtered columns, ordered from lowest to highest cardinality Note: This ordering is specific to Snowflake’s micro-partition architecture. Unlike traditional databases where high-cardinality columns are typically indexed first, Snowflake achieves better partition pruning when the lowest-cardinality column leads the clustering key.
Caching and latency
Amazon CloudFront, Amazon ElastiCache
Result cache, warehouse cache, query acceleration
Design query patterns to maximize Snowflake result cache hits; use Amazon ElastiCache for application-layer caching of frequently accessed Snowflake results
Pillar 5: Cost optimization and FinOps
Cost optimization across Snowflake and AWS involves two distinct billing models that you must manage together. AWS infrastructure costs follow a consumption and reservation model, and Snowflake charges are driven by compute credits and storage. Without a unified view, teams often optimize one application at the expense of the other. The following table addresses the key cost domains with integrated recommendations for reducing spend across both billing models.
Combine AWS Cost Explorer data with Snowflake credit consumption in an integrated FinOps dashboard; tag resources with matching cost-center labels
Compute efficiency
AWS Savings Plans, Amazon EC2 Spot Instances
Note: Savings Plans and Spot apply to customer-managed AWS compute (ETL pipelines, application tier) that feeds Snowflake, not to Snowflake warehouse compute itself.
Auto-suspend, warehouse right-sizing, serverless features
Pair Snowflake capacity commitments with AWS Savings Plans for predictable baseline; use auto-suspend aggressively for development warehouses
Time Travel retention optimization, transient tables
Align Snowflake Time Travel retention (1 day for development, 90 days for regulated data) with Amazon S3 lifecycle transitions to Amazon S3 Glacier
Pillar 6: Operational excellence
Operational excellence for Snowflake on AWS means building observability, automation, and incident response workflows that span both applications. Amazon CloudWatch, AWS Systems Manager, and Snowflake’s query history and task monitoring each provide partial visibility, but a well-operated architecture connects them into a coherent operational picture. The following table covers the core operational domains with integrated guidance for managing both applications as a single system.
Domain
AWS guidance
Snowflake guidance
Integrated recommendation
Monitoring
Amazon CloudWatch, AWS X-Ray, Amazon OpenSearch Service
Snowsight dashboards, Account Usage, query history
Export Snowflake metrics to Amazon CloudWatch using Amazon S3 integration for unified operational dashboards
Automation and IaC
AWS CloudFormation, AWS Cloud Development Kit (AWS CDK), Terraform
Snowflake Terraform provider, CI/CD pipelines
Manage Snowflake objects alongside AWS infrastructure in the same Terraform state; use CI/CD pipelines for database migration workflows
Trigger AWS Lambda auto-remediation from Snowflake resource monitor alerts via notification integrations and Amazon SNS
Pillar 7: Sustainability
This is the first joint ISV-AWS WAF lens to treat the sustainability pillar as a first-class concern. For Snowflake on AWS, sustainability decisions span AWS Region selection and energy efficiency choices on the infrastructure side, and warehouse consolidation, query efficiency, and data lifecycle management on the Snowflake side. The following table covers the sustainability domains with integrated recommendations that reduce the environmental footprint of your combined architecture.
Select AWS Regions aligned with sustainability goals for non-latency-sensitive Snowflake workloads; prefer secondary Regions with high renewable energy percentages for DR
Compute efficiency
AWS Compute Optimizer, Amazon EC2 Auto Scaling
Warehouse auto-suspend, serverless tasks
Enforce aggressive auto-suspend policies for development and batch workloads to alleviate idle compute; prefer serverless features for intermittent workloads
Minimize storage footprint by aligning Time Travel retention to actual recovery needs; replace full data copies with zero-copy clones for development and testing
Query efficiency
Batch and real-time processing best practices
Query profiling, clustering keys, materialized views, result caching
Optimize query patterns to reduce total compute-seconds; apply clustering keys to avoid full table scans
Three ways to use the lens
You can access the lens across three environments, each designed for a different workflow and team preference. Whether your team works primarily in the AWS Management Console, prefers an AI-assisted review inside an IDE, or operates within Snowflake, you can run a full Well-Architected review without switching contexts.
1. AWS Well-Architected Tool console
The lens is available directly in the AWS Well-Architected Tool console for structured reviews against your Snowflake on AWS workloads. A structured questionnaire covers all seven pillars with Snowflake-specific questions, and each best practice is risk-rated as High Risk, Medium Risk, or No Risk Identified. The review generates an improvement plan with prioritized actions and links to AWS and Snowflake documentation, milestone tracking to measure progress over time, and PDF or JSON export for stakeholder reporting and compliance evidence.
Choose Create custom lens, upload the downloaded JSON file, and choose Submit.
2. Kiro
For teams that prefer an AI-assisted, conversational approach, the Snowflake and AWS WAF Lens is available as a Kiro Power, an integrated capability within Kiro, the AI-powered IDE of AWS. The review runs conversationally inside the IDE with checkbox-based questions for each pillar, so you can avoid navigating a separate console. Findings are classified using a Red, Yellow, Green system for quick risk identification. Recommendations are organized into three time horizons: Now (1–2 weeks), Next (30–60 days), and Later (90 or more days). The output includes automation mapping for Proactive Health Checks and Blueprint defaults, and supports both customer-ready and internal delivery plan formats. Guidance is context-aware, accounting for your specific workload type, compliance requirements, and multi-Region needs.
In Kiro, choose Open Folder and select the unzipped folder.
Enter “Run a Snowflake and AWS WAF review” in the chat to begin.
3. Snowflake Cortex Code
In addition to using the AWS Well-Architected Tool and Kiro, you can also opt for the Cortex Code coding assistant path. The joint Well-Architected review is packaged as a Cortex Code skill that you can invoke to start the review process. When invoked, the skill opens with an architecture overview and asks how you want to proceed. You can run the full review interactively with AI-guided recommendations. Cortex Code is available as both a CLI and directly within Snowsight, so you can choose whichever fits your workflow.
Option A: Cortex Code CLI (local terminal)
To get started:
Download the Cortex Code zip file for AWS WAF Lens to a location that you want on your local computer and unzip it.
Open a terminal window on your computer and enter cortex skill add <path_to_the_unzipped_folder> at the shell prompt. The following screenshot shows an example.
Launch Cortex Code CLI by entering cortex at the shell prompt.
In the Cortex Code CLI chat window, enter invoke the joint-waf-aws-lens skill to get started.
Option B: Cortex Code in Snowsight (browser-based)
For teams that prefer to stay within the Snowflake UI, Cortex Code is also available directly in Snowsight, with no local install required.
In Snowsight, navigate to Projects > Workspaces and open (or create) a workspace where you want to run this skill.
Choose the Cortex Code icon in the lower-right corner of Snowsight to open the assistant panel.
Choose + Add context in the chat area of the assistant panel and select Upload Skill Folder(s), then choose the unzipped skill folder.
In the message box, enter run the joint-waf skill and press Enter to begin the review.
How the pillars come together
What makes this lens unique is that it integrates AWS infrastructure guidance directly into Snowflake-specific best practices.
Rather than running separate reviews for each application, the lens helps identify Snowflake architectural risks alongside the corresponding AWS remediation paths, showing where both layers need to be aligned.
Built for Snowflake on AWS
This lens reflects integrated expertise across both services:
Unified security model – AWS provides network isolation, encryption infrastructure, and identity federation. Snowflake provides data-layer protections like dynamic masking, row access policies, and Tri-Secret Secure. The lens shows how these layers compose into a coherent security posture.
FinOps integration – The cost pillar addresses the challenge of optimizing spend across two billing models: AWS infrastructure costs and Snowflake consumption costs.
Operational coherence – The operational excellence pillar bridges AWS-native observability (Amazon CloudWatch, Amazon OpenSearch Service) and Snowflake-native monitoring (Snowsight, Account Usage), so you can build connected dashboards and incident response workflows that span both services.
Sustainability as a first-class pillar – This is the first joint ISV-AWS WAF lens to include sustainability as a first-class pillar. It combines AWS Region selection strategies with warehouse consolidation, query efficiency optimization, and data lifecycle management.
Getting started with the Snowflake and AWS WAF Lens
To get the most out of your first review, start with the Security and Reliability pillars, where integrated AWS and Snowflake guidance surfaces the highest-impact findings for most production workloads. Use the improvement plan output to prioritize actions across your team, and export the results as PDF or JSON for stakeholder reporting and compliance evidence.
The following resources will help you go deeper on the AWS services and Snowflake capabilities referenced throughout this post.
This is the first release of the Snowflake and AWS WAF Lens, and we’re actively expanding its coverage with deeper guidance on Snowflake on AWS architecture.
We’re committed to making Snowflake on AWS well-architected in the cloud. Start your first review in either the AWS Well-Architected Tool or Snowflake Cortex Code CLI today, or reach out to your AWS account team or Snowflake account team to schedule a guided workshop.
Read all about the latest AWS security features, compliance updates, and hands-on resources in our new, monthly digest posts. You’ll find expert blog posts, new service capabilities, code samples, and workshops.
AWS Security Blog posts
This month’s AWS Security Blog posts covered AI security, network protection, identity management, compliance frameworks, and supply chain security. Read on for practical guidance on securing agentic AI workflows, filtering network traffic by category, defending against supply chain attacks, and more.
Enabling AI sovereignty on AWS Author: Stéphane Israël | Published: May 12, 2026 Learn how AWS delivers control and choice across the AI stack to help customers meet digital and AI sovereignty requirements.
Securing open proxies in your AWS environment Author: Dodd Mitchell | Published: May 4, 2026 Learn to identify and secure open proxies in your AWS environment to prevent abuse, protect your IP reputation, and control costs.
Introducing AI traffic analysis dashboards for AWS WAF Authors: Christopher Jen, Eitav Arditti, Kaustubh Phatak | Published: May 5, 2026 A new dashboard providing visibility into AI bot and agent activity including bot identification, intent classification, and access pattern analysis.
Authors: Frank Phillis, Lawton Pittenger | May 28, 2026
Learn to migrate your centralized AWS Network Firewall deployment to a AWS Transit Gateway-attached model, eliminating the inspection Amazon VPC and enabling flexible cost allocation.
Announcing the ISO 31000:2018 Risk Management on AWS compliance guide Authors: Jesse McMahan, Akanksha Chaturvedi, Mayur Jadhav, Juan Rodriguez, Sana Rahman | Published: May 1, 2026 A compliance guide providing practical guidance for establishing a risk management program using ISO 31000:2018 principles in AWS environments.
New compliance guide available: ISO/IEC 42001:2023 on AWS Authors: Abdul Javid, Amber Welch, Muhammad Sharief, Jonathan Jenkyn, Satish Uppalapati | Published: May 6, 2026 A compliance guide providing practical guidance for designing and operating an Artificial Intelligence Management System (AIMS) using AWS services.
Governing infrastructure as code using pattern-based policy as code Authors: Guptaji Teegela, Paul Keastead | May 19, 2026 Learn to use Open Policy Agent (OPA) in CI/CD pipelines to validate AWS infrastructure changes before deployment using recurring control patterns.
Detecting and preventing crypto mining in your AWS environment Authors: Jason Palmer, Nadia Mahmood | May 13, 2026 Learn to use Amazon GuardDuty to identify and mitigate cryptocurrency mining threats in your AWS environment with a multi-layered defense strategy.
This month brings 8 new AWS samples spanning application security, data protection, infrastructure security, governance, and AI security. From AI-powered security agents on Amazon Bedrock AgentCore to centralized AWS Config monitoring at scale, these repositories help you implement security best practices across your AWS environment.
Security review assistant Learn to deploy a multi-agent system on Amazon Bedrock AgentCore that automates Deliverable Security Reviews by combining architecture analysis, IaC code review, ASH vulnerability scanning, and compliance assessment into a single pipeline.
AWS Security Agent Recorder Learn to use a cross-browser extension that records the unique domains your web app contacts and auto-fills them into the AWS Security Agent penetration test configuration.
Data Protection
KMS access audit Learn to resolve and report who can use your AWS Key Management Service (KMS) keys across IAM policies, key policies, and grants, with IAM Identity Center resolution to identify the humans behind SSO roles.
Centralized AWS Config CI monitoring with Amazon CloudWatch Learn to centrally monitor AWS Config Configuration Item recording across all accounts in an AWS Organization using CloudWatch Cross-Account Observability, with dashboards showing top resource types, per-account volume, and conformance pack compliance.
CloudFormation Guard security analyzer Learn to deploy an AI agent powered by Amazon Bedrock AgentCore that scans CloudFormation resource documentation, identifies security-critical properties with risk levels, and generates ready-to-use cfn-guard 3.x rules for your CI/CD pipeline.
This month brings 1 new AWS Labs repository focused on governance, helping research institutions deploy secure, tagged infrastructure with self-service access and multi-account controls.
May 2026 shows AI security maturing from model-level controls to full-stack protection of agentic workflows. The posts and samples provide patterns for policy-based authorization with Cedar, network traffic filtering by category, and cross-account compliance monitoring. The security bulletins address vulnerabilities in SDKs, drivers, and developer tooling. Each resource includes deployment steps or runnable code so you can validate in your own environment before adopting. Subscribe to the AWS Security Blog RSS feed to receive updates as they publish, and revisit this digest monthly for a consolidated view of what changed and what to act on.
If you have feedback about this post, submit comments in the Comments section below.
Amazon Web Services (AWS) is pleased to announce that the Spring 2026 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 188 services over the 12-month period from April 1, 2025–March 31, 2026, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.
AWS is excited to be the first cloud service provider to offer compliance reports to customers in NIST’s Open Security Controls Assessment Language (OSCAL), an open-source, machine-readable (JSON) format for security information. The SOC report package in OSCAL format is now available separately in AWS Artifact, marking a milestone towards open, standards-based compliance automation. This machine-readable version of the SOC 1 & 2 reports enables workflow automation to reduce manual processing time and modernize security and compliance processes. Your use-cases for this content are innovative and we want to hear about them via the contact information found in the OSCAL report package.
AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.
We’re excited to announce that Amazon Web Services (AWS) has completed the S&P Global Know Your Third Party (KY3P) assessment of its security posture. This assessment demonstrates our continued commitment to meet the heightened expectations of cloud service providers. Customers can now use the AWS KY3P assessment to reduce their supplier due diligence burden.
KY3P, also known as the S&P Global Comprehensive Assessment (formerly TruSight), is a validated, evidence-based assessment designed to support regulatory compliance and efficient, standardized risk data exchange between AWS and our clients. KY3P’s globally recognized methodology provides organizations with enhanced visibility into supply chain risks by validating the actual implementation and operation of controls – not just policies or attestations.
As cloud adoption accelerates across industries, AWS has become a critical component of customers’ third-party environments. Regulated customers, such as those in the financial services sector, are held to high standards by regulators and auditors when it comes to exercising effective due diligence on third parties.
To better manage risks from their evolving third-party environments and drive operational efficiencies, many customers rely on third-party risk management services such as KY3P. In support of these efforts, AWS has completed its annual KY3P security posture assessment, conducted by KY3P security assessors.
KY3P’s risk assessment methodology includes over 200 controls across 26 control categories and nine risk domains. These topics include Privacy, Network Management, Logical Access Management, and Physical and Environmental Security. The assessment criteria were developed by a consortium of leading financial institutions.
Customers can use the KY3P results to map AWS against commonly used industry frameworks and standards, such as NIST CSF v2, PCI DSS 4.0, and ISO 27001:2022 to instantly gain visibility into controls coverage.
If you have feedback about this post, submit comments in the Comments section below. To learn more about our other compliance and security programs, see AWS Compliance Programs.
Our largest security services customers started the same way every customer does – with a click. They enabled Amazon GuardDuty, Amazon Inspector, AWS WAF, and AWS Security Hub, experienced the benefits in real time, and evaluated with transparent pay-as-you-go pricing. No RFP. No six-month evaluation. No multi-year commitment up front. Our field teams played a critical role in that growth, not by selling the first click, but by building the trusted relationships that turned early adoption into deep, long-term commitment. We believe customers should have this same frictionless adoption experience and flexibility for all best-in-class security products and that’s why we developed Security Hub Extended.
In our first post, we introduced Security Hub Extended, a significant expansion of Security Hub that brings together curated partner solutions in a single, unified experience. In our second post, we walked through how it works technically, including the onboarding flow, the pricing model, the unified operations layer built on the Open Cybersecurity Schema Framework (OCSF). In this post, I want to step back and talk about why we built it the way we did and why I believe the way enterprises discover, evaluate, and adopt security solutions is ready for a fundamental shift.
The shift
If you’ve ever tried to evaluate a new enterprise security product, you know the drill. Request a demo. Wait. Take the demo. Request a PoC. Wait for professional services (or your team to stop building) to set it up. Negotiate pricing, which isn’t published, so you’re starting blind. Loop in procurement. Sign a multi-year commitment. Then, months later, find out whether the product actually solves your problem in your unique environment.
Meanwhile, an ambitious security engineer on your team has already spun up an open-source tool, connected real data, and knows in two hours whether it’s going to work for your use cases. They didn’t need a slide deck. They needed a solution they could put their hands on.
A Fortune 500 CISO recently told me: “I spent 9 months procuring a security solution and it still doesn’t work the way the demo showed.” That frustration isn’t unique. It’s the norm.
This isn’t a criticism of the sales motion. Sales-led has evolved for good reason. Enterprise procurement is complex, products need customization, customers need support. I respect the craft and have poured a significant portion of my career into trying to perfect it. Even the most product-driven companies still need great sales, marketing, field enablement, and support.
It doesn’t change the fact that threats are evolving constantly, and defenders need the flexibility to discover and deploy new solutions as fast as the landscape shifts. Having the best solutions discoverable and deployable in that moment of need isn’t just a convenience, it’s a competitive advantage that customers are demanding. A new threat emerges, security teams have access to industry-leading solutions, and in a few clicks they’ve found their answer and are already seeing value. That’s the model every security company should be building toward.
What we’ve learned at AWS
At AWS, we’ve spent two decades learning what it takes to let customers adopt complex enterprise technology on their own terms, at massive scale. We haven’t always gotten it right, but we learn fast and adjust. The result is one of the largest cloud businesses in the world. I bring up that scale for one reason. It’s proof that complex, enterprise-grade technology can be adopted without requiring a traditional procurement gauntlet. Compute, storage, databases, AI/ML, networking, and yes, security — adopted all through a console, on each customer’s own timeline, and scaled when they were ready.
The proof is in the adoption
Amazon GuardDuty, Amazon Inspector, AWS Shield, AWS Security Hub are all available through the AWS Management Console. All pay-as-you-go. All activated with a click. Tens of thousands of customers rely on these security services today. When you make it easy to get started and deliver outcomes that earn confidence, expansion follows naturally.
These are sophisticated, enterprise-grade security solutions. And customers, from two-person startups to the world’s largest financial institutions, adopt them the same way. They try it, see the value, expand, and lean on the AWS team to go deeper.
We didn’t get here by accident, and we definitely didn’t get here without making mistakes. Building products that can be adopted and scaled on their own, without a sales engineer explaining away UX problems, without a solutions architect doing the first deployment, requires a different kind of product mindset. Time-to-value becomes your most important metric. Onboarding friction becomes your biggest enemy. Transparent pricing becomes non-negotiable. It’s hard. We’ve gotten a lot wrong along the way. And we’re still iterating.
But the results are clear. When customers adopt based on experience rather than commitment, they don’t just stay, they expand. They bring their teams. They become advocates. I’ve spent 15 years at AWS, the last 10 building security services like GuardDuty and Security Hub. When we launch a new security service or major feature, we consistently see rapid organic adoption at a pace that would be impossible through traditional sales cycles alone. These products are built to deliver value the moment customers turn them on and we make that as easy as we possibly can. That’s the scale a product-led motion unlocks.
Security Hub Extended
So, we asked ourselves: why can’t we build a similar approach that can expand to include industry leading partner solutions? Why can’t the CrowdStrikes, the Splunks, the Zscalers, and the fast-growing innovators solving tomorrow’s problems like Cyera, Noma, and 7AI also reach customers with the same frictionless motion that AWS services enjoy? Why can’t a security team that discovers a new threat on Monday have a proven solution deployed and delivering value by Tuesday? Our partners have built incredible products. What they haven’t always had is an avenue to put those products directly in the hands of the customers who need them most, at the moment they need them, at scale, in a way that feels as natural as turning on an AWS service. Not by replacing how our partners build or sell, but by giving them infrastructure that lets their products speak for themselves.
That’s what Security Hub Extended is. Security teams already using Security Hub can discover curated partner solutions right alongside their AWS security services. One click to evaluate, one click to deploy, pay-as-you-go pricing on your existing AWS bill with Enterprise Discount Program (EDP) discounts automatically applied. No separate procurement cycle. No long-term commitments required. Start fast, validate at scale, and commit for deeper discounts when you’re ready, versus making a three-year bet based on a few months of testing.
For customers, industry-leading enterprise security solutions become as easy to adopt as GuardDuty or WAF. For our partners, Security Hub Extended is a growth channel where the product leads and the customer experience mirrors what we’ve spent 20 years building at AWS. For the industry, it’s an invitation to reimagine what the relationship between a security product and a security practitioner can look like when you remove the friction standing between them.
But Security Hub Extended isn’t just a simpler way to buy security products. It’s a unified solution. When a customer enables a solution through Extended, we’re working toward an experience where AWS handles the rest. Sensors that deploy automatically across Amazon EC2, Amazon EKS, and AWS Fargate workloads using the same mechanism that powers GuardDuty Runtime Monitoring. IAM roles that provision across a customer’s Organization in one click. Resource inventory is automated from day one – S3 buckets, databases, AI workloads – without manual work.
Once enabled, solutions in Security Hub Extended emit findings in OCSF, automatically aggregated in Security Hub alongside findings from GuardDuty, Amazon Inspector, and every other AWS security service. Security Hub applies risk scoring and correlated risk analytics across all of them. AWS-native and third-party findings together, weighted and prioritized as a single view of your security posture. For example, an endpoint detection from CrowdStrike, correlated with a credential theft in GuardDuty, and a data access event from Cyera, produces an attack path that none of those solutions can produce alone. The correlation uses AWS context (IAM topology, VPC exposure, resource criticality) to improve the context of each attack path for security analysts. Deploying a solution through Security Hub Extended doesn’t add another pane of glass. It deepens the intelligence of the one you already have.
We’re also building toward automated response. Customers will be able to opt in to pre-built playbooks that take action through AWS-native services when a threat is detected, such as isolating compromised resources, revoking credentials, or containing active threats. The goal is detect-to-respond in seconds, not the hours it takes to context-switch across five consoles and two ticketing systems.
Where we are and where we’re headed
We’re still in the first inning — or Day 1, as we like to say at Amazon. We launched in February 2026 with 14 partners, now 21, spanning endpoint, identity, email, network, data, browser, cloud, AI, and security operations, and we’re continuously working backwards from customers as we operationalize for scale. We are building this because our customers asked for it. We’re learning alongside our partners and customers every week, identifying what works, what needs improvement, where the friction still lives, and iterating quickly.
We’re building and delivering at the speed of our customers. That means shipping fast, iterating faster, and not waiting for perfection. We’re not where we want to be just yet, and we need your feedback to get us there. What’s encouraging is that our partners aren’t waiting to be asked. They’re investing in this alongside us. Not because we’re demanding it, but because they see the same thing we do, that companies that make it effortless for customers to get started are the ones that will win at scale.
The early signals are encouraging. Customer response has exceeded our expectations, and the feedback we hear most often is that the procurement simplification and flexibility of pay-as-you-go with public pricing alone, even before the unified operations and data normalization benefits, is a meaningful differentiator.
If you’re a security leader: Security Hub Extended is live now. Log into Security Hub, look for the Security Hub Extended Plan (or visit the Security Hub Extended Pricing Page), and explore what’s available for your use cases. Start with what solves your most urgent problem. Pay-as-you-go, no commitment. Your team will tell you if it’s working in days, not months.
The vision is bigger than what’s live today, and we’re iterating fast. Share your feedback on AWS re:Post for Security Hub, reach out through contact AWS Support, or connect with me directly.
The financial services industry (FSI) is using AI to transform how financial institutions serve their customers. AI solutions can help proactively manage portfolios, automatically refinance mortgages when rates decrease, and negotiate insurance premiums for customers.
As the regulatory environment and leading practices continue to evolve, we will provide further updates on the AWS Security Blog and AWS Compliance Center. You can also reach out to your AWS account team for help finding the resources you need.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
 . Azure findings are prioritized next to your AWS findings using the same finding format, automation, and response workflows, so your team works from one understanding of risk across your entire estate. Azure resources are priced at the same rates as equivalent AWS resources with no additional fees, and there’s an independent 30-day free trial. To learn more, see the