Tag Archives: Uncategorized

NSA on Authentication Hacks (Related to SolarWinds Breach)

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/nsa-on-authentication-hacks-related-to-solarwinds-breach.html

The NSA has published an advisory outlining how “malicious cyber actors” are “are manipulating trust in federated authentication environments to access protected data in the cloud.” This is related to the SolarWinds hack I have previously written about, and represents one of the techniques the SVR is using once it has gained access to target networks.

From the summary:

Malicious cyberactors are abusing trust in federated authentication environments to access protected data. The exploitation occurs after the actors have gained initial access to a victim’s on-premises network. The actors leverage privileged access in the on-premises environment to subvert the mechanisms that the organization uses to grant access to cloud and on-premises resources and/or to compromise administrator credentials with the ability to manage cloud resources. The actors demonstrate two sets of tactics, techniques,and procedures (TTP) for gaining access to the victim network’s cloud resources, often with a particular focus on organizational email.

In the first TTP, the actors compromise on-premises components of a federated SSO infrastructure and steal the credential or private key that is used to sign Security Assertion Markup Language (SAML) tokens(TA0006, T1552, T1552.004). Using the private keys, the actors then forge trusted authentication tokens to access cloud resources. A recent NSA Cybersecurity Advisory warned of actors exploiting a vulnerability in VMware Access and VMware Identity Manager that allowed them to perform this TTP and abuse federated SSO infrastructure.While that example of this TTP may have previously been attributed to nation-state actors, a wealth of actors could be leveraging this TTP for their objectives. This SAML forgery technique has been known and used by cyber actors since at least 2017.

In a variation of the first TTP, if the malicious cyber actors are unable to obtain anon-premises signing key, they would attempt to gain sufficient administrative privileges within the cloud tenant to add a malicious certificate trust relationship for forging SAML tokens.

In the second TTP, the actors leverage a compromised global administrator account to assign credentials to cloud application service principals (identities for cloud applications that allow the applications to be invoked to access other cloud resources). The actors then invoke the application’s credentials for automated access to cloud resources (often email in particular) that would otherwise be difficult for the actors to access or would more easily be noticed as suspicious (T1114, T1114.002).

This is an ongoing story, and I expect to see a lot more about TTP — nice acronym there — in coming weeks.

Related: Tom Bossert has a scathing op-ed on the breach. Jack Goldsmith’s essay is worth reading. So is Nick Weaver’s.

US Schools Are Buying Cell Phone Unlocking Systems

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/us-schools-are-buying-cell-phone-unlocking-systems.html

Gizmodo is reporting that schools in the US are buying equipment to unlock cell phones from companies like Cellebrite:

Gizmodo has reviewed similar accounting documents from eight school districts, seven of which are in Texas, showing that administrators paid as much $11,582 for the controversial surveillance technology. Known as mobile device forensic tools (MDFTs), this type of tech is able to siphon text messages, photos, and application data from student’s devices. Together, the districts encompass hundreds of schools, potentially exposing hundreds of thousands of students to invasive cell phone searches.

The eighth district was in Los Angeles.

More on the SolarWinds Breach

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/more-on-the-solarwinds-breach.html

The New York Times has more details.

About 18,000 private and government users downloaded a Russian tainted software update –­ a Trojan horse of sorts ­– that gave its hackers a foothold into victims’ systems, according to SolarWinds, the company whose software was compromised.

Among those who use SolarWinds software are the Centers for Disease Control and Prevention, the State Department, the Justice Department, parts of the Pentagon and a number of utility companies. While the presence of the software is not by itself evidence that each network was compromised and information was stolen, investigators spent Monday trying to understand the extent of the damage in what could be a significant loss of American data to a foreign attacker.

It’s unlikely that the SVR (a successor to the KGB) penetrated all of those networks. But it is likely that they penetrated many of the important ones. And that they have buried themselves into those networks, giving them persistent access even if this vulnerability is patched. This is a massive intelligence coup for the Russians and failure for the Americans, even if no classified networks were touched.

Meanwhile, CISA has directed everyone to remove SolarWinds from their networks. This is (1) too late to matter, and (2) likely to take many months to complete. Probably the right answer, though.

This is almost too stupid to believe:

In one previously unreported issue, multiple criminals have offered to sell access to SolarWinds’ computers through underground forums, according to two researchers who separately had access to those forums.

One of those offering claimed access over the Exploit forum in 2017 was known as “fxmsp” and is wanted by the FBI “for involvement in several high-profile incidents,” said Mark Arena, chief executive of cybercrime intelligence firm Intel471. Arena informed his company’s clients, which include U.S. law enforcement agencies.

Security researcher Vinoth Kumar told Reuters that, last year, he alerted the company that anyone could access SolarWinds’ update server by using the password “solarwinds123”

“This could have been done by any attacker, easily,” Kumar said.

Neither the password nor the stolen access is considered the most likely source of the current intrusion, researchers said.

That last sentence is important, yes. But the sloppy security practice is likely not an isolated incident, and speaks to the overall lack of security culture at the company.

And I noticed that SolarWinds has removed its customer page, presumably as part of its damage control efforts. I quoted from it. Did anyone save a copy?

EDITED TO ADD: Both the Wayback Machine and Brian Krebs have saved the SolarWinds customer page.

Mexican Drug Cartels with High-Tech Spyware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/mexican-drug-cartels-with-high-tech-spyware.html

Sophisticated spyware, sold by surveillance tech companies to Mexican government agencies, are ending up in the hands of drug cartels:

As many as 25 private companies — including the Israeli company NSO Group and the Italian firm Hacking Team — have sold surveillance software to Mexican federal and state police forces, but there is little or no regulation of the sector — and no way to control where the spyware ends up, said the officials.

Lots of details in the article. The cyberweapons arms business is immoral in many ways. This is just one of them.

Using container image support for AWS Lambda with AWS SAM

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/using-container-image-support-for-aws-lambda-with-aws-sam/

At AWS re:Invent 2020, AWS Lambda released Container Image Support for Lambda functions. This new feature allows developers to package and deploy Lambda functions as container images of up to 10 GB in size. With this release, AWS SAM also added support to manage, build, and deploy Lambda functions using container images.

In this blog post, I walk through building a simple serverless application that uses Lambda functions packaged as container images with AWS SAM. I demonstrate creating a new application and highlight changes to the AWS SAM template specific to container image support. I then cover building the image locally for debugging in addition to eventual deployment. Finally, I show using AWS SAM to handle packaging and deploying Lambda functions from a developer’s machine or a CI/CD pipeline.

Push to invoke lifecycle

Push to invoke lifecycle

The process for creating a Lambda function packaged as a container requires only a few steps. A developer first creates the container image and tags that image with the appropriate label. The image is then uploaded to an Amazon Elastic Container Registry (ECR) repository using docker push.

During the Lambda create or update process, the Lambda service pulls the image from ECR, optimizes the image for use, and deploys the image to the Lambda service. Once this, and any other configuration processes are complete, the Lambda function is then in Active status and ready to be invoked. The AWS SAM CLI manages most of these steps for you.

Prerequisites

The following tools are required in this walkthrough:

Create the application

Use the terminal and follow these steps to create a serverless application:

  1. Enter sam init.
  2. For Template source, select option one for AWS Quick Start Templates.
  3. For Package type, choose option two for Image.
  4. For Base image, select option one for amazon/nodejs12.x-base.
  5. Name the application demo-app.
Demonstration of sam init

Demonstration of sam init

Exploring the application

Open the template.yaml file in the root of the project to see the new options available for container image support. The AWS SAM template has two new values that are required when working with container images. PackageType: Image tells AWS SAM that this function is using container images for packaging.

AWS SAM template

AWS SAM template

The second set of required data is in the Metadata section that helps AWS SAM manage the container images. When a container is created, a new tag is added to help identify that image. By default, Docker uses the tag, latest. However, AWS SAM passes an explicit tag name to help differentiate between functions. That tag name is a combination of the Lambda function resource name, and the DockerTag value found in the Metadata. Additionally, the DockerContext points to the folder containing the function code and Dockerfile identifies the name of the Dockerfile used in building the container image.

In addition to changes in the template.yaml file, AWS SAM also uses the Docker CLI to build container images. Each Lambda function has a Dockerfile that instructs Docker how to construct the container image for that function. The Dockerfile for the HelloWorldFunction is at hello-world/Dockerfile.

Local development of the application

AWS SAM provides local development support for zip-based and container-based Lambda functions. When using container-based images, as you modify your code, update the local container image using sam build. AWS SAM then calls docker build using the Dockerfile for instructions.

Dockerfile for Lambda function

Dockerfile for Lambda function

In the case of the HelloWorldFunction that uses Node.js, the Docker command:

  1. Pulls the latest container base image for nodejs12.x from the Amazon Elastic Container Registry Public.
  2. Copies the app.js code and package.json files to the container image.
  3. Installs the dependencies inside the container image.
  4. Sets the invocation handler.
  5. Creates and tags new version of the local container image.

To build your application locally on your machine, enter:

sam build

The results are:

Results for sam build

Results for sam build

Now test the code by locally invoking the HelloWorldFunction using the following command:

sam local invoke HelloWorldFunction

The results are:

Results for sam local invoke

Results for sam local invoke

You can also combine these commands and add flags for cached and parallel builds:

sam build --cached --parallel && sam local invoke HelloWorldFunction

Deploying the application

There are two ways to deploy container-based Lambda functions with AWS SAM. The first option is to deploy from AWS SAM using the sam deploy command. The deploy command tags the local container image, uploads it to ECR, and then creates or updates your Lambda function. The second method is the sam package command used in continuous integration and continuous delivery or deployment (CI/CD) pipelines, where the deployment process is separate from the artifact creation process.

AWS SAM package tags and uploads the container image to ECR but does not deploy the application. Instead, it creates a modified version of the template.yaml file with the newly created container image location. This modified template is later used to deploy the serverless application using AWS CloudFormation.

Deploying from AWS SAM with the guided flag

Before you can deploy the application, use the AWS CLI to create a new ECR repository to store the container image for the HelloWorldFunction.

Run the following command from a terminal:

aws ecr create-repository --repository-name demo-app-hello-world \
--image-tag-mutability IMMUTABLE --image-scanning-configuration scanOnPush=true

This command creates a new ECR repository called demo-app-hello-world. The –image-tag-mutability IMMUTABLE option prevents overwriting tags. The –image-scanning-configuration scanOnPush=true enables automated vulnerability scanning whenever a new image is pushed to the repository. The output is:

Amazon ECR creation output

Amazon ECR creation output

Make a note of the repositoryUri as you need it in the next step.

Before you can push your images to this new repository, ensure that you have logged in to the managed Docker service that ECR provides. Update the bracketed tokens with your information and run the following command in the terminal:

aws ecr get-login-password --region <region> | docker login --username AWS \
--password-stdin <account id>.dkr.ecr.<region>.amazonaws.com

You can also install the Amazon ECR credentials helper to help facilitate Docker authentication with Amazon ECR.

After building the application locally and creating a repository for the container image, you can deploy the application. The first time you deploy an application, use the guided version of the sam deploy command and follow these steps:

  1. Type sam deploy --guided, or sam deploy -g.
  2. For Stack Name, enter demo-app.
  3. Choose the same Region that you created the ECR repository in.
  4. Enter the Image Repository for the HelloWorldFunction (this is the repositoryUri of the ECR repository).
  5. For Confirm changes before deploy and Allow SAM CLI IAM role creation, keep the defaults.
  6. For HelloWorldFunction may not have authorization defined, Is this okay? Select Y.
  7. Keep the defaults for the remaining prompts.
Results of sam deploy --guided

Results of sam deploy –guided

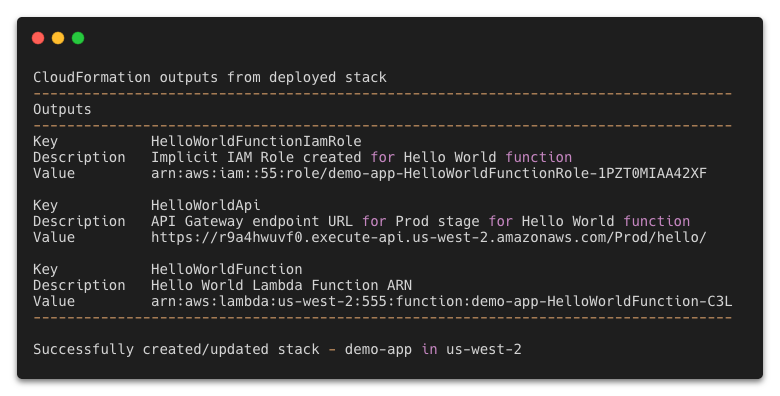
AWS SAM uploads the container images to the ECR repo and deploys the application. During this process, you see a changeset along with the status of the deployment. When the deployment is complete, the stack outputs are then displayed. Use the HelloWorldApi endpoint to test your application in production.

Deploy outputs

Deploy outputs

When you use the guided version, AWS SAM saves the entered data to the samconfig.toml file. For subsequent deployments with the same parameters, use sam deploy. If you want to make a change, use the guided deployment again.

This example demonstrates deploying a serverless application with a single, container-based Lambda function in it. However, most serverless applications contain more than one Lambda function. To work with an application that has more than one Lambda function, follow these steps to add a second Lambda function to your application:

  1. Copy the hello-world directory using the terminal command cp -R hello-world hola-world
  2. Replace the contents of the template.yaml file with the following
    AWSTemplateFormatVersion: '2010-09-09'
    Transform: AWS::Serverless-2016-10-31
    Description: demo app
      
    Globals:
      Function:
        Timeout: 3
    
    Resources:
      HelloWorldFunction:
        Type: AWS::Serverless::Function
        Properties:
          PackageType: Image
          Events:
            HelloWorld:
              Type: Api
              Properties:
                Path: /hello
                Method: get
        Metadata:
          DockerTag: nodejs12.x-v1
          DockerContext: ./hello-world
          Dockerfile: Dockerfile
          
      HolaWorldFunction:
        Type: AWS::Serverless::Function
        Properties:
          PackageType: Image
          Events:
            HolaWorld:
              Type: Api
              Properties:
                Path: /hola
                Method: get
        Metadata:
          DockerTag: nodejs12.x-v1
          DockerContext: ./hola-world
          Dockerfile: Dockerfile
    
    Outputs:
      HelloWorldApi:
        Description: "API Gateway endpoint URL for Prod stage for Hello World function"
        Value: !Sub "https://${ServerlessRestApi}.execute-api.${AWS::Region}.amazonaws.com/Prod/hello/"
      HolaWorldApi:
        Description: "API Gateway endpoint URL for Prod stage for Hola World function"
        Value: !Sub "https://${ServerlessRestApi}.execute-api.${AWS::Region}.amazonaws.com/Prod/hola/"
  3. Replace the contents of hola-world/app.js with the following
    let response;
    exports.lambdaHandler = async(event, context) => {
        try {
            response = {
                'statusCode': 200,
                'body': JSON.stringify({
                    message: 'hola world',
                })
            }
        }
        catch (err) {
            console.log(err);
            return err;
        }
        return response
    };
  4. Create an ECR repository for the HolaWorldFunction
    aws ecr create-repository --repository-name demo-app-hola-world \
    --image-tag-mutability IMMUTABLE --image-scanning-configuration scanOnPush=true
  5. Run the guided deploy to add the second repository:
    sam deploy -g

The AWS SAM guided deploy process allows you to provide the information again but prepopulates the defaults with previous values. Update the following:

  1. Keep the same stack name, Region, and Image Repository for HelloWorldFunction.
  2. Use the new repository for HolaWorldFunction.
  3. For the remaining steps, use the same values from before. For Lambda functions not to have authorization defined, enter Y.
Results of sam deploy --guided

Results of sam deploy –guided

Deploying in a CI/CD pipeline

Companies use continuous integration and continuous delivery (CI/CD) pipelines to automate application deployment. Because the process is automated, using an interactive process like a guided AWS SAM deployment is not possible.

Developers can use the packaging process in AWS SAM to prepare the artifacts for deployment and produce a separate template usable by AWS CloudFormation. The package command is:

sam package --output-template-file packaged-template.yaml \
--image-repository 5555555555.dkr.ecr.us-west-2.amazonaws.com/demo-app

For multiple repositories:

sam package --output-template-file packaged-template.yaml \ 
--image-repositories HelloWorldFunction=5555555555.dkr.ecr.us-west-2.amazonaws.com/demo-app-hello-world \
--image-repositories HolaWorldFunction=5555555555.dkr.ecr.us-west-2.amazonaws.com/demo-app-hola-world

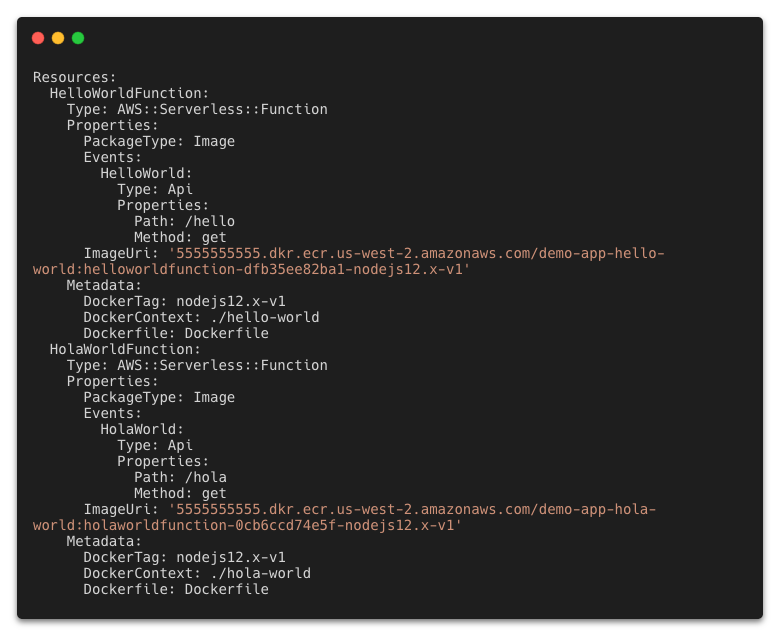
Both cases create a file called packaged-template.yaml. The Lambda functions in this template have an added tag called ImageUri that points to the ECR repository and a tag for the Lambda function.

Packaged template

Packaged template

Using sam package to generate a separate CloudFormation template enables developers to separate artifact creation from application deployment. The deployment process can then be placed in an isolated stage allowing for greater customization and observability of the pipeline.

Conclusion

Container image support for Lambda enables larger application artifacts and the ability to use container tooling to manage Lambda images. AWS SAM simplifies application management by bringing these tools into the serverless development workflow.

In this post, you create a container-based serverless application in using command lines in the terminal. You create ECR repositories and associate them with functions in the application. You deploy the application from your local machine and package the artifacts for separate deployment in a CI/CD pipeline.

To learn more about serverless and AWS SAM, visit the Sessions with SAM series at s12d.com/sws and find more resources at serverlessland.com.

#ServerlessForEveryone

Zodiac Killer Cipher Solved

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/zodiac-killer-cipher-solved.html

The SF Chronicle is reporting (more details here), and the FBI is confirming, that a Melbourne mathematician and team has decrypted the 1969 message sent by the Zodiac Killer to the newspaper.

There’s no paper yet, but there are a bunch of details in the news articles.

Here’s an interview with one of the researchers:

Cryptologist David Oranchak, who has been trying to crack the notorious “340 cipher” (it contains 340 characters) for more than a decade, made a crucial breakthrough earlier this year when applied mathematician Sam Blake came up with about 650,000 different possible ways in which the code could be read. From there, using code-breaking software designed by Jarl Van Eycke, the team’s third member, they came up with a small number of valuable clues that helped them piece together a message in the cipher

How the SolarWinds Hackers Bypassed Duo’s Multi-Factor Authentication

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/how-the-solarwinds-hackers-bypassed-duo-multi-factor-authentication.html

This is interesting:

Toward the end of the second incident that Volexity worked involving Dark Halo, the actor was observed accessing the e-mail account of a user via OWA. This was unexpected for a few reasons, not least of which was the targeted mailbox was protected by MFA. Logs from the Exchange server showed that the attacker provided username and password authentication like normal but were not challenged for a second factor through Duo. The logs from the Duo authentication server further showed that no attempts had been made to log into the account in question. Volexity was able to confirm that session hijacking was not involved and, through a memory dump of the OWA server, could also confirm that the attacker had presented cookie tied to a Duo MFA session named duo-sid.

Volexity’s investigation into this incident determined the attacker had accessed the Duo integration secret key (akey) from the OWA server. This key then allowed the attacker to derive a pre-computed value to be set in the duo-sid cookie. After successful password authentication, the server evaluated the duo-sid cookie and determined it to be valid. This allowed the attacker with knowledge of a user account and password to then completely bypass the MFA set on the account. It should be noted this is not a vulnerability with the MFA provider and underscores the need to ensure that all secrets associated with key integrations, such as those with an MFA provider, should be changed following a breach.

Again, this is not a Duo vulnerability. From ArsTechnica:

While the MFA provider in this case was Duo, it just as easily could have involved any of its competitors. MFA threat modeling generally doesn’t include a complete system compromise of an OWA server. The level of access the hacker achieved was enough to neuter just about any defense.

Another Massive Russian Hack of US Government Networks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/another-massive-russian-hack-of-us-government-networks.html

The press is reporting a massive hack of US government networks by sophisticated Russian hackers.

Officials said a hunt was on to determine if other parts of the government had been affected by what looked to be one of the most sophisticated, and perhaps among the largest, attacks on federal systems in the past five years. Several said national security-related agencies were also targeted, though it was not clear whether the systems contained highly classified material.

[…]

The motive for the attack on the agency and the Treasury Department remains elusive, two people familiar with the matter said. One government official said it was too soon to tell how damaging the attacks were and how much material was lost, but according to several corporate officials, the attacks had been underway as early as this spring, meaning they continued undetected through months of the pandemic and the election season.

The attack vector seems to be a malicious update in SolarWinds’ “Orion” IT monitoring platform, which is widely used in the US government (and elsewhere).

SolarWinds’ comprehensive products and services are used by more than 300,000 customers worldwide, including military, Fortune 500 companies, government agencies, and education institutions. Our customer list includes:

  • More than 425 of the US Fortune 500
  • All ten of the top ten US telecommunications companies
  • All five branches of the US Military
  • The US Pentagon, State Department, NASA, NSA, Postal Service, NOAA, Department of Justice, and the Office of the President of the United States
  • All five of the top five US accounting firms
  • Hundreds of universities and colleges worldwide

I’m sure more details will become public over the next several weeks.

EDITED TO ADD (12/15): More news.

Should There Be Limits on Persuasive Technologies?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/should-there-be-limits-on-persuasive-technologies.html

Persuasion is as old as our species. Both democracy and the market economy depend on it. Politicians persuade citizens to vote for them, or to support different policy positions. Businesses persuade consumers to buy their products or services. We all persuade our friends to accept our choice of restaurant, movie, and so on. It’s essential to society; we couldn’t get large groups of people to work together without it. But as with many things, technology is fundamentally changing the nature of persuasion. And society needs to adapt its rules of persuasion or suffer the consequences.

Democratic societies, in particular, are in dire need of a frank conversation about the role persuasion plays in them and how technologies are enabling powerful interests to target audiences. In a society where public opinion is a ruling force, there is always a risk of it being mobilized for ill purposes — ­such as provoking fear to encourage one group to hate another in a bid to win office, or targeting personal vulnerabilities to push products that might not benefit the consumer.

In this regard, the United States, already extremely polarized, sits on a precipice.

There have long been rules around persuasion. The US Federal Trade Commission enforces laws that claims about products “must be truthful, not misleading, and, when appropriate, backed by scientific evidence.” Political advertisers must identify themselves in television ads. If someone abuses a position of power to force another person into a contract, undue influence can be argued to nullify that agreement. Yet there is more to persuasion than the truth, transparency, or simply applying pressure.

Persuasion also involves psychology, and that has been far harder to regulate. Using psychology to persuade people is not new. Edward Bernays, a pioneer of public relations and nephew to Sigmund Freud, made a marketing practice of appealing to the ego. His approach was to tie consumption to a person’s sense of self. In his 1928 book Propaganda, Bernays advocated engineering events to persuade target audiences as desired. In one famous stunt, he hired women to smoke cigarettes while taking part in the 1929 New York City Easter Sunday parade, causing a scandal while linking smoking with the emancipation of women. The tobacco industry would continue to market lifestyle in selling cigarettes into the 1960s.

Emotional appeals have likewise long been a facet of political campaigns. In the 1860 US presidential election, Southern politicians and newspaper editors spread fears of what a “Black Republican” win would mean, painting horrific pictures of what the emancipation of slaves would do to the country. In the 2020 US presidential election, modern-day Republicans used Cuban Americans’ fears of socialism in ads on Spanish-language radio and messaging on social media. Because of the emotions involved, many voters believed the campaigns enough to let them influence their decisions.

The Internet has enabled new technologies of persuasion to go even further. Those seeking to influence others can collect and use data about targeted audiences to create personalized messaging. Tracking the websites a person visits, the searches they make online, and what they engage with on social media, persuasion technologies enable those who have access to such tools to better understand audiences and deliver more tailored messaging where audiences are likely to see it most. This information can be combined with data about other activities, such as offline shopping habits, the places a person visits, and the insurance they buy, to create a profile of them that can be used to develop persuasive messaging that is aimed at provoking a specific response.

Our senses of self, meanwhile, are increasingly shaped by our interaction with technology. The same digital environment where we read, search, and converse with our intimates enables marketers to take that data and turn it back on us. A modern day Bernays no longer needs to ferret out the social causes that might inspire you or entice you­ — you’ve likely already shared that by your online behavior.

Some marketers posit that women feel less attractive on Mondays, particularly first thing in the morning — ­and therefore that’s the best time to advertise cosmetics to them. The New York Times once experimented by predicting the moods of readers based on article content to better target ads, enabling marketers to find audiences when they were sad or fearful. Some music streaming platforms encourage users to disclose their current moods, which helps advertisers target subscribers based on their emotional states.

The phones in our pockets provide marketers with our location in real time, helping deliver geographically relevant ads, such as propaganda to those attending a political rally. This always-on digital experience enables marketers to know what we are doing­ — and when, where, and how we might be feeling at that moment.

All of this is not intended to be alarmist. It is important not to overstate the effectiveness of persuasive technologies. But while many of them are more smoke and mirrors than reality, it is likely that they will only improve over time. The technology already exists to help predict moods of some target audiences, pinpoint their location at any given time, and deliver fairly tailored and timely messaging. How far does that ability need to go before it erodes the autonomy of those targeted to make decisions of their own free will?

Right now, there are few legal or even moral limits on persuasion­ — and few answers regarding the effectiveness of such technologies. Before it is too late, the world needs to consider what is acceptable and what is over the line.

For example, it’s been long known that people are more receptive to advertisements made with people who look like them: in race, ethnicity, age, gender. Ads have long been modified to suit the general demographic of the television show or magazine they appear in. But we can take this further. The technology exists to take your likeness and morph it with a face that is demographically similar to you. The result is a face that looks like you, but that you don’t recognize. If that turns out to be more persuasive than coarse demographic targeting, is that okay?

Another example: Instead of just advertising to you when they detect that you are vulnerable, what if advertisers craft advertisements that deliberately manipulate your mood? In some ways, being able to place ads alongside content that is likely to provoke a certain emotional response enables advertisers to do this already. The only difference is that the media outlet claims it isn’t crafting the content to deliberately achieve this. But is it acceptable to actively prime a target audience and then to deliver persuasive messaging that fits the mood?

Further, emotion-based decision-making is not the rational type of slow thinking that ought to inform important civic choices such as voting. In fact, emotional thinking threatens to undermine the very legitimacy of the system, as voters are essentially provoked to move in whatever direction someone with power and money wants. Given the pervasiveness of digital technologies, and the often instant, reactive responses people have to them, how much emotion ought to be allowed in persuasive technologies? Is there a line that shouldn’t be crossed?

Finally, for most people today, exposure to information and technology is pervasive. The average US adult spends more than eleven hours a day interacting with media. Such levels of engagement lead to huge amounts of personal data generated and aggregated about you­ — your preferences, interests, and state of mind. The more those who control persuasive technologies know about us, what we are doing, how we are feeling, when we feel it, and where we are, the better they can tailor messaging that provokes us into action. The unsuspecting target is grossly disadvantaged. Is it acceptable for the same services to both mediate our digital experience and to target us? Is there ever such thing as too much targeting?

The power dynamics of persuasive technologies are changing. Access to tools and technologies of persuasion is not egalitarian. Many require large amounts of both personal data and computation power, turning modern persuasion into an arms race where the better resourced will be better placed to influence audiences.

At the same time, the average person has very little information about how these persuasion technologies work, and is thus unlikely to understand how their beliefs and opinions might be manipulated by them. What’s more, there are few rules in place to protect people from abuse of persuasion technologies, much less even a clear articulation of what constitutes a level of manipulation so great it effectively takes agency away from those targeted. This creates a positive feedback loop that is dangerous for society.

In the 1970s, there was widespread fear about so-called subliminal messaging, which claimed that images of sex and death were hidden in the details of print advertisements, as in the curls of smoke in cigarette ads and the ice cubes of liquor ads. It was pretty much all a hoax, but that didn’t stop the Federal Trade Commission and the Federal Communications Commission from declaring it an illegal persuasive technology. That’s how worried people were about being manipulated without their knowledge and consent.

It is time to have a serious conversation about limiting the technologies of persuasion. This must begin by articulating what is permitted and what is not. If we don’t, the powerful persuaders will become even more powerful.

This essay was written with Alicia Wanless, and previously appeared in Foreign Policy.

Upcoming Speaking Engagements

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2020/12/upcoming-speaking-engagements-4.html

This is a current list of where and when I am scheduled to speak:

The list is maintained on this page.

Authentication Failure

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/authentication-failure.html

This is a weird story of a building owner commissioning an artist to paint a mural on the side of his building — except that he wasn’t actually the building’s owner.

The fake landlord met Hawkins in person the day after Thanksgiving, supplying the paint and half the promised fee. They met again a couple of days later for lunch, when the job was mostly done. Hawkins showed him photographs. The patron seemed happy. He sent Hawkins the rest of the (sorry) dough.

But when Hawkins invited him down to see the final result, his client didn’t answer the phone. Hawkins called again. No answer. Hawkins emailed. Again, no answer.

[…]

Two days later, Hawkins got a call from the real Comte. And that Comte was not happy.

Comte says that he doesn’t believe Hawkins’s story, but I don’t think I would have demanded to see a photo ID before taking the commission.

Friday Squid Blogging: Newly Identified Ichthyosaur Species Probably Ate Squid

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/friday-squid-blogging-newly-identified-ichthyosaur-species-probably-ate-squid.html

This is a deep-diving species that “fed on small prey items such as squid.”

Academic paper.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

A Cybersecurity Policy Agenda

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/a-cybersecurity-policy-agenda.html

The Aspen Institute’s Aspen Cybersecurity Group — I’m a member — has released its cybersecurity policy agenda for the next four years.

The next administration and Congress cannot simultaneously address the wide array of cybersecurity risks confronting modern society. Policymakers in the White House, federal agencies, and Congress should zero in on the most important and solvable problems. To that end, this report covers five priority areas where we believe cybersecurity policymakers should focus their attention and resources as they contend with a presidential transition, a new Congress, and massive staff turnover across our nation’s capital.

  • Education and Workforce Development
  • Public Core Resilience
  • Supply Chain Security
  • Measuring Cybersecurity
  • Promoting Operational Collaboration

Lots of detail in the 70-page report.

Finnish Data Theft and Extortion

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/finnish-data-theft-and-extortion.html

The Finnish psychotherapy clinic Vastaamo was the victim of a data breach and theft. The criminals tried extorting money from the clinic. When that failed, they started extorting money from the patients:

Neither the company nor Finnish investigators have released many details about the nature of the breach, but reports say the attackers initially sought a payment of about 450,000 euros to protect about 40,000 patient records. The company reportedly did not pay up. Given the scale of the attack and the sensitive nature of the stolen data, the case has become a national story in Finland. Globally, attacks on health care organizations have escalated as cybercriminals look for higher-value targets.

[…]

Vastaamo said customers and employees had “personally been victims of extortion” in the case. Reports say that on Oct. 21 and Oct. 22, the cybercriminals began posting batches of about 100 patient records on the dark web and allowing people to pay about 500 euros to have their information taken down.

FireEye Hacked

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/fireeye-hacked.html

FireEye was hacked by — they believe — “a nation with top-tier offensive capabilities”:

During our investigation to date, we have found that the attacker targeted and accessed certain Red Team assessment tools that we use to test our customers’ security. These tools mimic the behavior of many cyber threat actors and enable FireEye to provide essential diagnostic security services to our customers. None of the tools contain zero-day exploits. Consistent with our goal to protect the community, we are proactively releasing methods and means to detect the use of our stolen Red Team tools.

We are not sure if the attacker intends to use our Red Team tools or to publicly disclose them. Nevertheless, out of an abundance of caution, we have developed more than 300 countermeasures for our customers, and the community at large, to use in order to minimize the potential impact of the theft of these tools.

We have seen no evidence to date that any attacker has used the stolen Red Team tools. We, as well as others in the security community, will continue to monitor for any such activity. At this time, we want to ensure that the entire security community is both aware and protected against the attempted use of these Red Team tools. Specifically, here is what we are doing:

  • We have prepared countermeasures that can detect or block the use of our stolen Red Team tools.
  • We have implemented countermeasures into our security products.
  • We are sharing these countermeasures with our colleagues in the security community so that they can update their security tools.
  • We are making the countermeasures publicly available on our GitHub.
  • We will continue to share and refine any additional mitigations for the Red Team tools as they become available, both publicly and directly with our security partners.

Consistent with a nation-state cyber-espionage effort, the attacker primarily sought information related to certain government customers. While the attacker was able to access some of our internal systems, at this point in our investigation, we have seen no evidence that the attacker exfiltrated data from our primary systems that store customer information from our incident response or consulting engagements, or the metadata collected by our products in our dynamic threat intelligence systems. If we discover that customer information was taken, we will contact them directly.

From the New York Times:

The hack was the biggest known theft of cybersecurity tools since those of the National Security Agency were purloined in 2016 by a still-unidentified group that calls itself the ShadowBrokers. That group dumped the N.S.A.’s hacking tools online over several months, handing nation-states and hackers the “keys to the digital kingdom,” as one former N.S.A. operator put it. North Korea and Russia ultimately used the N.S.A.’s stolen weaponry in destructive attacks on government agencies, hospitals and the world’s biggest conglomerates ­- at a cost of more than $10 billion.

The N.S.A.’s tools were most likely more useful than FireEye’s since the U.S. government builds purpose-made digital weapons. FireEye’s Red Team tools are essentially built from malware that the company has seen used in a wide range of attacks.

Russia is presumed to be the attacker.

Reuters article. Boing Boing post. Slashdot thread. Wired article.

Oblivious DNS-over-HTTPS

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/oblivious-dns-over-https.html

This new protocol, called Oblivious DNS-over-HTTPS (ODoH), hides the websites you visit from your ISP.

Here’s how it works: ODoH wraps a layer of encryption around the DNS query and passes it through a proxy server, which acts as a go-between the internet user and the website they want to visit. Because the DNS query is encrypted, the proxy can’t see what’s inside, but acts as a shield to prevent the DNS resolver from seeing who sent the query to begin with.

IETF memo.

The paper:

Abstract: The Domain Name System (DNS) is the foundation of a human-usable Internet, responding to client queries for host-names with corresponding IP addresses and records. Traditional DNS is also unencrypted, and leaks user information to network operators. Recent efforts to secure DNS using DNS over TLS (DoT) and DNS over HTTPS (DoH) havebeen gaining traction, ostensibly protecting traffic and hiding content from on-lookers. However, one of the criticisms ofDoT and DoH is brought to bear by the small number of large-scale deployments (e.g., Comcast, Google, Cloudflare): DNS resolvers can associate query contents with client identities in the form of IP addresses. Oblivious DNS over HTTPS (ODoH) safeguards against this problem. In this paper we ask what it would take to make ODoH practical? We describe ODoH, a practical DNS protocol aimed at resolving this issue by both protecting the client’s content and identity. We implement and deploy the protocol, and perform measurements to show that ODoH has comparable performance to protocols like DoH and DoT which are gaining widespread adoption,while improving client privacy, making ODoH a practical privacy enhancing replacement for the usage of DNS.

Slashdot thread.

Amazon HealthLake Stores, Transforms, and Analyzes Health Data in the Cloud

Post Syndicated from Harunobu Kameda original https://aws.amazon.com/blogs/aws/new-amazon-healthlake-to-store-transform-and-analyze-petabytes-of-health-and-life-sciences-data-in-the-cloud/

Healthcare organizations collect vast amounts of patient information every day, from family history and clinical observations to diagnoses and medications. They use all this data to try to compile a complete picture of a patient’s health information in order to provide better healthcare services. Currently, this data is distributed across various systems (electronic medical records, laboratory systems, medical image repositories, etc.) and exists in dozens of incompatible formats.

Emerging standards, such as Fast Healthcare Interoperability Resources (FHIR), aim to address this challenge by providing a consistent format for describing and exchanging structured data across these systems. However, much of this data is unstructured information contained in medical records (e.g., clinical records), documents (e.g., PDF lab reports), forms (e.g., insurance claims), images (e.g., X-rays, MRIs), audio (e.g., recorded conversations), and time series data (e.g., heart electrocardiogram) and it is challenging to extract this information.

It can take weeks or months for a healthcare organization to collect all this data and prepare it for transformation (tagging and indexing), structuring, and analysis. Furthermore, the cost and operational complexity of doing all this work is prohibitive for most healthcare organizations.

Many data to analyze

Today, we are happy to announce Amazon HealthLake, a fully managed, HIPAA-eligible service, now in preview, that allows healthcare and life sciences customers to aggregate their health information from different silos and formats into a centralized AWS data lake. HealthLake uses machine learning (ML) models to normalize health data and automatically understand and extract meaningful medical information from the data so all this information can be easily searched. Then, customers can query and analyze the data to understand relationships, identify trends, and make predictions.

How It Works
Amazon HealthLake supports copying your data from on premises to the AWS Cloud, where you can store your structured data (like lab results) as well as unstructured data (like clinical notes), which HealthLake will tag and structure in FHIR. All the data is fully indexed using standard medical terms so you can quickly and easily query, search, analyze, and update all of your customers’ health information.

Overview of HealthLake

With HealthLake, healthcare organizations can collect and transform patient health information in minutes and have a complete view of a patients medical history, structured in the FHIR industry standard format with powerful search and query capabilities.

From the AWS Management Console, healthcare organizations can use the HealthLake API to copy their on-premises healthcare data to a secure data lake in AWS with just a few clicks. If your source system is not configured to send data in FHIR format, you can use a list of AWS partners to easily connect and convert your legacy healthcare data format to FHIR.

HealthLake is Powered by Machine Learning
HealthLake uses specialized ML models such as natural language processing (NLP) to automatically transform raw data. These models are trained to understand and extract meaningful information from unstructured health data.

For example, HealthLake can accurately identify patient information from medical histories, physician notes, and medical imaging reports. It then provides the ability to tag, index, and structure the transformed data to make it searchable by standard terms such as medical condition, diagnosis, medication, and treatment.

Queries on tens of thousands of patient records are very simple. For example, a healthcare organization can create a list of diabetic patients based on similarity of medications by selecting “diabetes” from the standard list of medical conditions, selecting “oral medications” from the treatment menu, and refining the gender and search.

Healthcare organizations can use Juypter Notebook templates in Amazon SageMaker to quickly and easily run analysis on the normalized data for common tasks like diagnosis predictions, hospital re-admittance probability, and operating room utilization forecasts. These models can, for example, help healthcare organizations predict the onset of disease. With just a few clicks in a pre-built notebook, healthcare organizations can apply ML to their historical data and predict when a diabetic patient will develop hypertension in the next five years. Operators can also build, train, and deploy their own ML models on data using Amazon SageMaker directly from the AWS management console.

Let’s Create Your Own Data Store and Start to Test
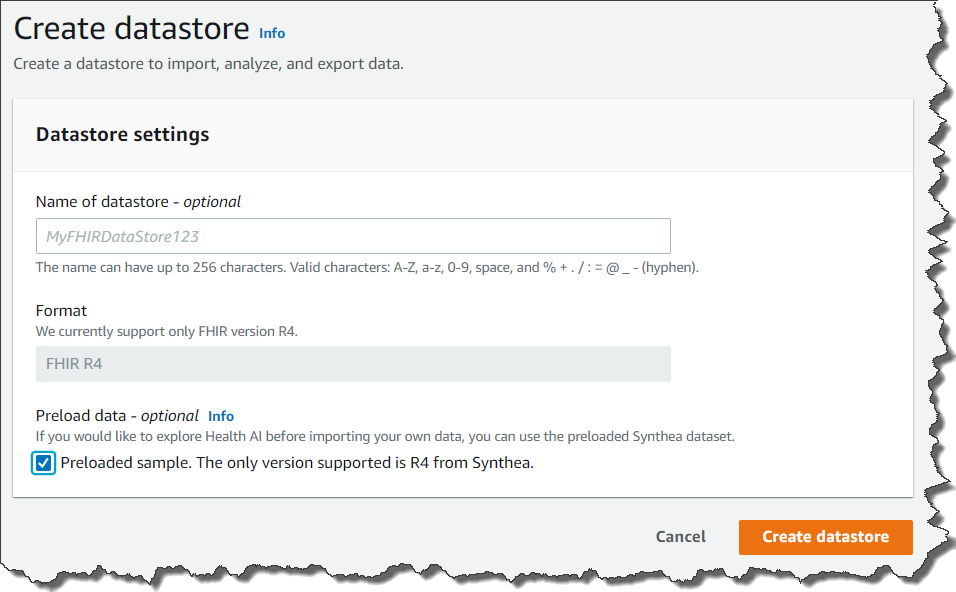
Starting to use HealthLake is simple. You access AWS Management Console, and click select Create a datastore.

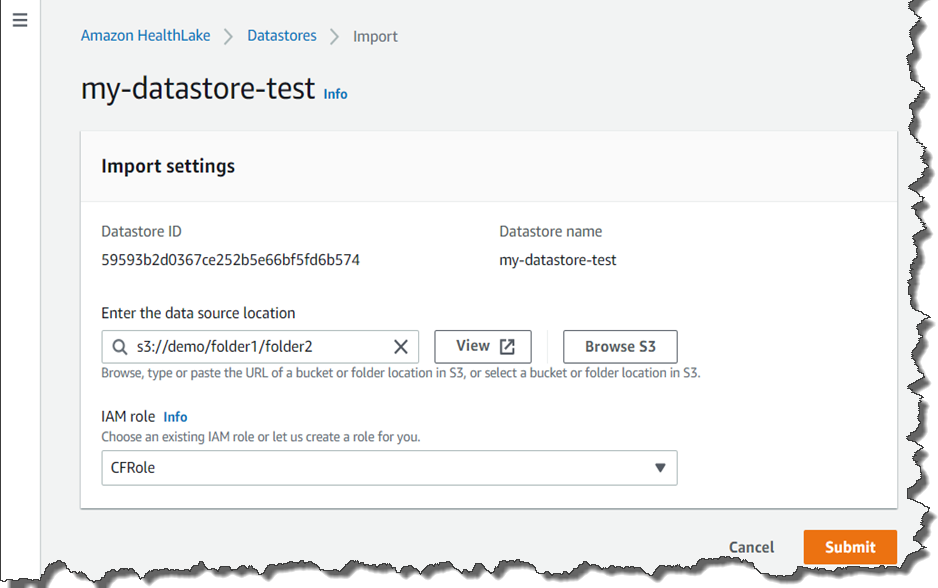
If you click Preload data, HealthLake will load test data and you can start to test its features. You can also upload your own data if you already have FHIR 4 compliant data. You upload it to S3 buckets, and import it to set its bucket name.

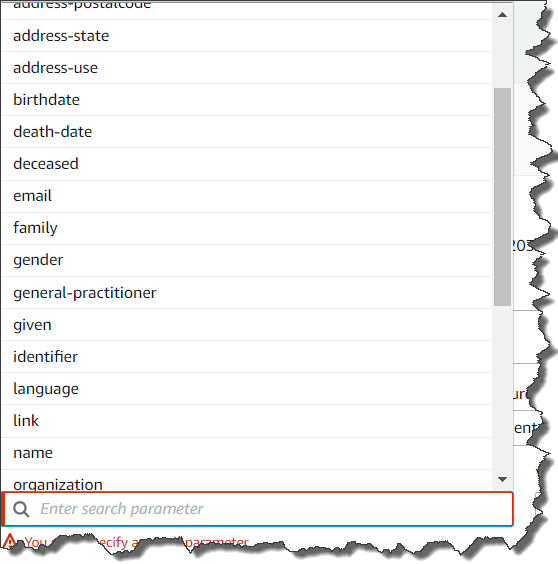
Once your Data Store is created, you can perform a Search, Create, Read, Update or Delete FHIR Query Operation. For example, if you need a list of every patient located in New York, your query setting looks like the screenshots below. As per the FHIR specification, deleted data is only hidden from analysis and results; it is not deleted from the service, only versioned.

Creating Query


You can choose Add search parameter for more nested conditions of the query as shown below.

Amazon HealthLake is Now in Preview
Amazon HealthLake is in preview starting today in US East (N. Virginia). Please check our web site and technical documentation for more information.

– Kame

Hiding Malware in Social Media Buttons

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/hiding-malware-in-social-media-buttons.html

Clever tactic:

This new malware was discovered by researchers at Dutch cyber-security company Sansec that focuses on defending e-commerce websites from digital skimming (also known as Magecart) attacks.

The payment skimmer malware pulls its sleight of hand trick with the help of a double payload structure where the source code of the skimmer script that steals customers’ credit cards will be concealed in a social sharing icon loaded as an HTML ‘svg’ element with a ‘path’ element as a container.

The syntax for hiding the skimmer’s source code as a social media button perfectly mimics an ‘svg’ element named using social media platform names (e.g., facebook_full, twitter_full, instagram_full, youtube_full, pinterest_full, and google_full).

A separate decoder deployed separately somewhere on the e-commerce site’s server is used to extract and execute the code of the hidden credit card stealer.

This tactic increases the chances of avoiding detection even if one of the two malware components is found since the malware loader is not necessarily stored within the same location as the skimmer payload and their true purpose might evade superficial analysis.

Friday Squid Blogging: Bigfin Squid Found in Australian Waters

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/friday-squid-blogging-bigfin-squid-found-in-australian-waters.html

A bigfin squid has been foundand filmed — in Australian waters for the first time.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.