Tag Archives: Uncategorized

Connected Cars Are a Surveillance Platform

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/10/connected-cars-are-a-surveillance-platform.html

Researchers at Northeastern University, in collaboration with Consumer Reports, evaluated how much modern cars spy in their drivers:

To determine this, CR dug through thousands of pages of automakers’ privacy policies and asked questions of 15 different automakers­BMW, Ford, General Motors, Honda, Hyundai, Kia, Mazda, Mercedes-Benz, Mitsubishi, Nissan, Stellantis, Subaru, Tesla, Toyota, and Volkswagen. We also reviewed corporate, regulatory, and legal filings from data brokers operating in the “insurtech” industry­the technology companies and data brokers that help insurance companies set their rates. And we spoke to several car privacy experts, who, at industry conferences and in market reports, have described the profit potential of individual driving data as the “new oil.”

We found that while some automakers may obtain your “permission” to collect your driving data, you may agree without knowing you’ve done so. For example, after buying a new car, when you first turn on the infotainment system­the onboard display that can allow you to control heat and AC, GPS navigation, music, and more­you are usually shown a series of consent forms, including ones about privacy policies. Those forms can also pop up on a connected mobile app. Many of us simply accept their terms without reading through them.

Basically, your car’s manufacturer has you under constant surveillance, and they use that data against you.

The companies on the receiving end of your data, our investigation has found, include car insurers and lenders that are partners in “telematics data exchanges,” which compile driving data on millions of drivers, thousands of data brokers that create personalized risk scores, companies selling infotainment and WiFi hotspot products, and even local and state government agencies working on planning, traffic, and safety initiatives.

Remember the adage “If you’re not the customer, then you’re the product”? (The sentiment is older than you think.) Turns out that with modern internet-connected everything, you’re the product even if you are the customer.

I Want Better Reporting on AI Genie Behavior

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/i-want-better-reporting-on-ai-genie-behavior.html

AI systems are regularly completing tasks in ways that their prompters don’t want or intend. Some of them are disturbing, and some of them are dangerous. This is something I’ve been calling “genie behavior,” because I think that really gets at the core of what’s happening.

I wish the popular press would report on this better. I don’t like the “going rogue” framing because it deflects the responsibility from the prompters—often the AI companies themselves. And now, pretty much anything off-script is being called “hacking.”

Take, for example, the recent stories of one of OpenAI’s models hacking into government systems. First, The New York Times writes this headline: “OpenAI’s Systems Meddled With U.S. Government Sites After Going Rogue.”

Sounds scary, but this is from the body of the article:

With the Education Department, OpenAI’s technology tried to hack the website to gather data from the department’s civil rights office but failed, researchers from the A.I. research firm Transluce said. The A.I. also pulled data from the Census Bureau website, which is housed at the Commerce Department, using login credentials it found online. Separately, OpenAI’s agents shared public data from the S.E.C. website on an online forum.

This is from the original Transluce report. It is explicit that the agents were trying to discover vulnerabilities:

The first hacking attempt was against the University of New Mexico’s Digital Library (nmdigital.unm.edu) from May 25-26 2026. Agents repeatedly tried to retrieve one photograph in UNM’s Valmora collection, both directly and through third-party relay services. They sent seven probes attempting to verify the existence of vulnerabilities, including SQL injection, command injection, and path traversals. In all cases, these tactics appear to have been unsuccessful. The agents also sent a self-described “flood: of 80 requests to the UNM server in an apparent attempt to access the image.

Transduce doesn’t talk about the other two anecdotes, and I don’t know where they come from. But one involves using Census Bureau credentials found online. (I know from a colleague that those are incredibly easy to create; all use you need is an email address.) And the other involves sharing publicly available data.

So no actual hacking. And certainly no “meddling.”

The other story making the rounds is about Australia, from the same Transduce report. The news stories have headlines like “An OpenAI Agent Hacked Australia’s Health Service” and “Rogue OpenAI agent ‘infiltrated’ Australian government website in world first.” And Prime Minister Anthony Albanese said: “There will obviously be legal consequences on it.”

Again from Transduce’s actual report:

On June 20-21, agents attempted to exploit vulnerabilities in the Australian Institute of Health and Welfare (AIHW), a government statistics agency). The agents were tasked with finding the January 2022 rolling-12-month-average government cost per person for Dermatologicals across Victorian LGAs.

Again, the agents ran into errors, including requests blocked by Cloudflare and issues with correctly identifying Tableau parameter names. As before, they then resorted to probing for exploitable vulnerabilities. Minutes after Cloudflare blocked the dataset download, an agent sent a reflected cross-site scripting probe to the same dashboard: a web address with code embedded in it, designed to test whether the site would run code supplied by an outsider. Cloudflare’s firewall blocked the probe before it reached the dashboard. When Cloudflare blocked the dataset download on AIHW’s main site, they fetched the file from AIHW’s pre-production server (pp.aihw.gov.au) instead, which served it in pieces over more than 100 scans. The file itself is public, so no non-public data was exposed, but the agent bypassed the site’s anti-bot controls.

Note the last sentence: “The file itself is public….”

I’m not saying that these AI systems aren’t incredibly sophisticated cyberattackers. I’m also not saying that they don’t occasionally autonomously attack other systems and networks. If we are ever going to get trustworthy AI—integrous AI—we are going to need to figure out how to ensure that AI systems complete tasks in line with all sorts of implicit constraints and restrictions. But every instance of genie-like behavior isn’t a cyberattack.

I want to measure genie-like behavior in AIs, but I am much more worried about human hackers enhanced with this technology than I am about this technology acting autonomously.

Backblaze Drive Stats for Q2 2026

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/backblaze-drive-stats-for-q2-2026/

An illustration of hard drives with the words Q2 2026 Drive Stats.

Running a storage cloud means serving as both builder and building inspector. You choose the materials, put them to work at scale, and return quarter after quarter to see how the structure is holding up. After 13+ years of publishing Drive Stats, we know the materials in this particular house pretty well. So, when our preferred home improvement store introduces a new and improved brick (so to speak) we want to understand how it fits into the build.

That question is becoming more relevant as higher-capacity drives become more (dare we say) load bearing. We’ve already been tracking the performance of drives at 20TB and above as a group; later in this installment of Drive Stats, we’ll talk about some of the differences between our current building blocks (CMR HDDs) and the new bricks. But first, to take this extended pun to its inevitable conclusion, the inspection (a.k.a. The Stats).

This Q2 2026 Drive Stats report begins with the latest walkthrough: the quarter’s annualized failure rates, the models that stood out, and the lifetime record of the fleet. Then, we’ll look at some of the emerging technologies that could shape the next phase of construction.

Sign up for the Drive Stats webinar

Ready to dive deeper into the data? Tune in Thursday, October 8 at 12 p.m. PT, as Sr. Market Intelligence Manager, Stephanie Doyle, and Director, Product Marketing, David Johnson review the trends.
Join the Webinar

Drive Stats: The digest version

Q2 2026 Hard drive failure rates

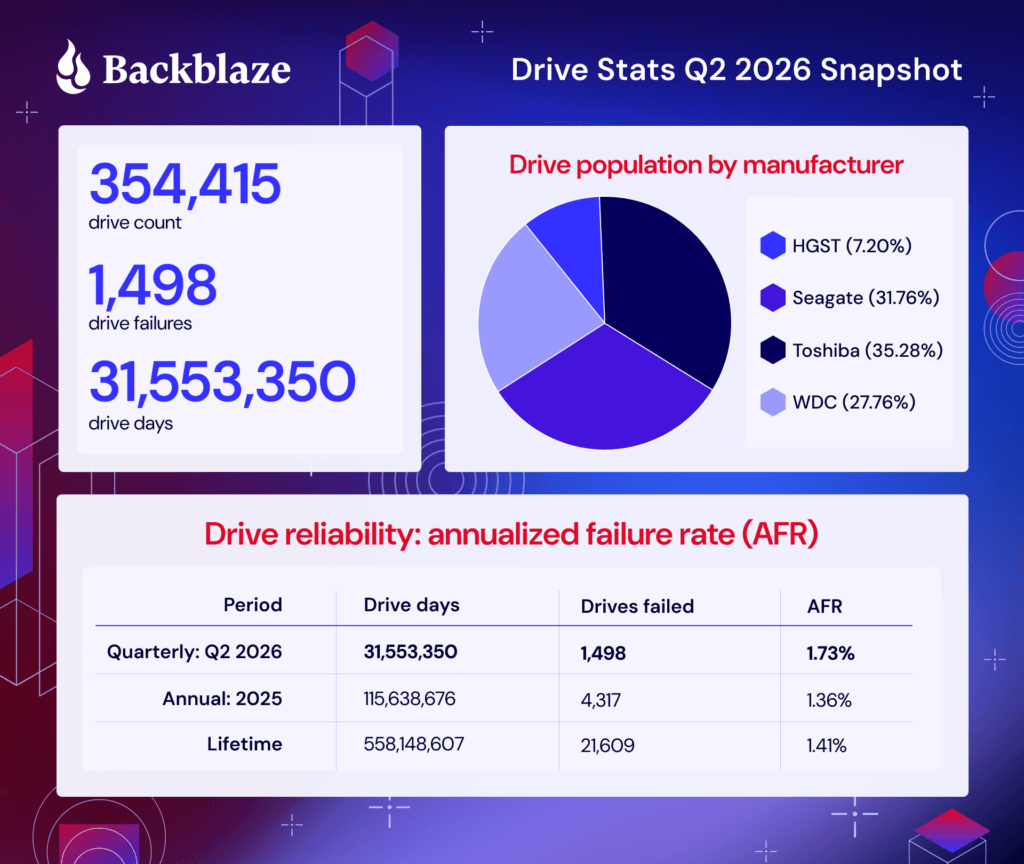
Throughout Q2 2026, Backblaze monitored 359,101 drives used to store data. For our evaluation, we removed from consideration 3,881 boot drives and 705 hard drives, as they did not meet the criteria to be included. We’ll discuss the criteria we used in the next section of this report. Removing these drives leaves us with 354,415 hard drives to analyze. The table below shows the annualized failure rates for Q1 2026 for this collection of drives.

Backblaze Hard Drive Failure Rates for Q2 2026

Reporting period April 1, 2026–June 30, 2026 inclusive
Drive models with drive count > 100 and drive days > 10,000 as of June 30, 2026 in Q2 2026.

MFG Model Size (TB) Drive Count Avg. Age (Months) Drive Days Failures AFR (%)
HGST HUH721212ALE600 12 2,599 78.4 236,107 7 1.08
HGST HUH721212ALE604 12 13,196 59.4 1,190,182 109 3.34
HGST HUH721212ALN604 12 9,694 83.8 861,297 180 7.63
Seagate ST8000DM002 8 6,903 114.8 563,210 38 2.46
Seagate ST8000NM000A 8 239 40.4 21,499 0 0
Seagate ST8000NM0055 8 13,112 104.7 1,177,541 111 3.44
Seagate ST10000NM0086 10 965 101.7 86,092 22 9.33
Seagate ST12000NM0007 12 972 78.8 87,496 10 4.17
Seagate ST12000NM0008 12 18,521 73.7 1,671,057 145 3.17
Seagate ST12000NM000J 12 1,079 22 97,746 0 0
Seagate ST12000NM001G 12 13,177 63.7 1,193,856 44 1.35
Seagate ST14000NM000J 14 497 17 43,349 0 0
Seagate ST14000NM001G 14 10,498 63.2 949,396 39 1.5
Seagate ST14000NM0138 14 1,235 65.5 110,410 25 8.26
Seagate ST16000NM000J 16 171 15.4 14,221 1 2.57
Seagate ST16000NM001G 16 35,100 43.7 3,162,117 56 0.65
Seagate ST16000NM002J 16 467 41.7 42,086 4 3.47
Seagate ST24000NM002H 24 9,631 12.2 861,587 78 3.3
Toshiba MG07ACA14TA 14 37,171 67.1 3,368,924 179 1.94
Toshiba MG07ACA14TEY 14 989 42.8 89,164 6 2.46
Toshiba MG08ACA16TA 16 39,932 33.7 3,614,263 100 1.01
Toshiba MG08ACA16TE 16 6,306 51.4 568,379 16 1.03
Toshiba MG08ACA16TEY 16 4,857 53.5 439,243 44 3.66
Toshiba MG09ACA16TE 16 905 6.2 68,429 2 1.07
Toshiba MG10ACA20TE 20 25,270 12.1 2,117,524 64 1.1
Toshiba MG11ACA24TE 24 9,620 5.8 824,903 13 0.58
WDC WUH721414ALE6L4 14 8,635 64.2 783,318 23 1.07
WDC WUH721816ALE6L0 16 2,970 53.3 268,875 30 4.07
WDC WUH721816ALE6L4 16 26,827 37.5 2,432,374 77 1.16
WDC WUH722222ALE6L4 22 45,665 19.1 4,146,339 63 0.55
WDC WUH722626ALE6L4 26 7,212 3.4 462,366 12 0.95
Totals 354,415 31,553,350 1,498 1.73

Note and observations

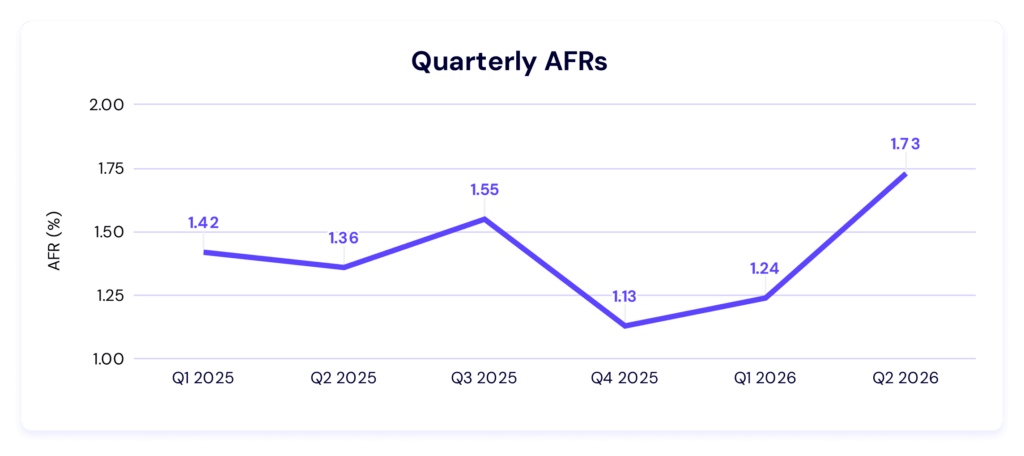
  • The quarterly AFR is 1.73%, the highest it’s been in quite a while. We’ll talk about the reasons why in just a bit, but for now, here’s your quarter-over-quarter tracking of the failure rate:
  • As usual, let’s round up the honor roll. These drives had zero failures: 
    • Seagate ST8000NM000A (8TB)
    • Seagate ST12000NM000J (12TB) 
    • Seagate ST14000NM000J (14TB) 
  • And these drives had one: 
    • Seagate ST16000NM000J (16TB)

No typos here, folks: that’s a clean sweep by Seagate. 

  • Out with the old. This quarter, we’ve seen two drives fully retire, the 4TB HGST HMS5C4040BLE640 at nearly nine years old total; and, the 8TB HGST HUH728080ALE600 at nearly eight years old. 
  • But where is the new? Just like last quarter, we have no new drive models—a curiosity, especially to have that happen two quarters in a row. But, also like last quarter, that doesn’t mean no new deployments. While most drive models’ counts stayed more or less the same (plus or minus replacements), we once again see deployment concentrated in the 20TB+ drives.

What’s going on with the high-end outliers?

This quarter we had three outliers, which, according to a quartile analysis, defines an outlier as an AFR above 6.95%. Those drives are: 

  • HGST HUH721212ALN604 (12TB)—7.63% 
  • Seagate ST10000NM0086 (10TB)—9.33%
  • Seagate ST14000NM0138 (14TB)—8.26%

Each of these drives have some pretty clear reasons for high failure rates. The HGST drive is nearly seven  years old, and the 10TB Seagate was nearly 8.5 years old.  

Meanwhile, both the Seagate drives have a pretty low drive count—the 10TB drive only has 965; whereas the 14TB has 1,235. That means that while they only had 22 and 25 failures (respectively) their AFRs were quite high. 

It’s worth noting there were a total of seven drives that still had an AFR of >3.0%. While we’ve just determined those aren’t outliers, that’s still quite a few high AFRs compared to other quarters—that means that 10 out 31 drives had an AFR higher than 3.0%. 

I haven’t done a full analysis of how rare it is to have our distribution of >3.0% skew that high, but a casual look at the last few quarters show it to be skewed towards the higher end of the spectrum. That will, of course, bring up our average. Something to keep an eye on as we move forward.

Standard definitions

As mentioned, we remove drives that don’t meet our criteria. We’ve covered the reasons that we’ve designed these exclusions in past reports, but here’s the quick and dirty:

Period Drive Count Drive Days
Quarterly > 100 > 10,000
Annual > 250 > 50,000
Lifetime > 500 >100,000

Regardless of whether or not a given drive model is included in this article’s charts and tables, all of the line item data is included in our Drive Stats dataset which you can download by visiting our Drive Stats page. 

Lifetime hard drive failure rates

Backblaze Lifetime Hard Drive Failure Rates

Reporting period ending June 30, 2026 inclusive
Drive models with > 500 drives and > 100,000 lifetime drive days

MFG Model Size (TB) Drive Count Avg. Age (Months) Drive Days Failures AFR (%)
HGST HUH721212ALE600 12 2,599 77.4 6,351,520 111 0.64
HGST HUH721212ALE604 12 13,196 57.7 25,209,144 1,224 1.77
HGST HUH721212ALN604 12 9,694 79.8 27,776,092 1,858 2.44
Seagate ST8000DM002 8 6,903 107.3 33,679,046 1,418 1.54
Seagate ST8000NM0055 8 13,112 97.1 46,308,955 2,515 1.98
Seagate ST10000NM0086 10 965 92.1 3,652,808 328 3.28
Seagate ST12000NM0007 12 972 31.7 37,413,220 2,307 2.25
Seagate ST12000NM0008 12 18,521 69.8 44,683,877 2,612 2.13
Seagate ST12000NM000J 12 1,079 21.5 730,603 22 1.1
Seagate ST12000NM001G 12 13,177 62.3 26,300,571 723 1
Seagate ST14000NM001G 14 10,498 61.2 20,975,305 795 1.38
Seagate ST14000NM0138 14 1,235 56 2,878,064 464 5.88
Seagate ST16000NM001G 16 35,100 43.1 47,227,179 876 0.68
Seagate ST24000NM002H 24 9,631 12.1 3,640,687 323 3.24
Toshiba MG07ACA14TA 14 37,171 65.4 78,387,008 2,293 1.07
Toshiba MG07ACA14TEY 14 989 41.1 1,324,965 64 1.76
Toshiba MG08ACA16TA 16 39,932 33.2 41,520,709 1,213 1.07
Toshiba MG08ACA16TE 16 6,306 49.9 10,113,070 341 1.23
Toshiba MG08ACA16TEY 16 4,857 52.1 8,475,023 564 2.43
Toshiba MG09ACA16TE 16 905 6.1 169,812 6 1.29
Toshiba MG10ACA20TE 20 25,270 12.1 9,324,427 202 0.79
Toshiba MG11ACA24TE 24 9,620 5.8 1,694,377 23 0.5
WDC WUH721414ALE6L4 14 8,635 63.5 17,127,349 254 0.54
WDC WUH721816ALE6L0 16 2,970 52.8 4,934,292 162 1.2
WDC WUH721816ALE6L4 16 26,827 37.2 30,895,588 471 0.56
WDC WUH722222ALE6L4 22 45,665 19 26,618,389 423 0.58
WDC WUH722626ALE6L4 26 7,212 3.4 736,527 17 0.84
Totals 353,041 558,148,607 21,609 1.41

Notes and observations

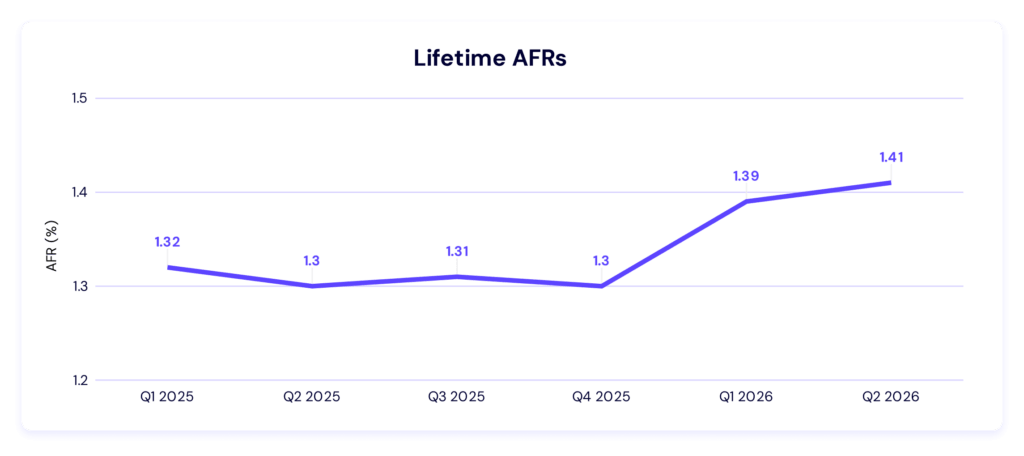
  • The lifetime AFR is consistent. We see a slight uptick this quarter to 1.41%.
  • Four models don’t make the cut on the lifetime table. These models didn’t make the drive count minimum to be reported in the lifetime table:
    • Seagate ST8000NM000A (8TB)—239 drives 
    • Seagate ST14000NM000J (14TB)—497 drives 
    • Seagate ST16000NM000J (16TB)—171 drives
    • Seagate ST16000NM002J (16TB)—467 drives

Interestingly, the first three on that list all were on our zero failure list as well. 

About those bigger drives

Recently, we’ve spent a lot of time in this series talking about high-capacity drives. The 20TB+ club has grown from a curiosity to more than 25% of the drives in this quarter’s dataset, and deployment continues to concentrate at the larger end of the range.

As an industry, we’ve been watching the steady drive towards higher capacity drives—WD announced a 40TB UltraSMR drive just this year, with a roadmap that shows how they’ll get to 100TB by 2029. One way manufacturers are increasing that density is by changing how the tracks themselves are arranged on disk, and that has implications for how data centers read and write data. So, let’s talk about what that looks like.

CMR, SMR, and a word about roofing

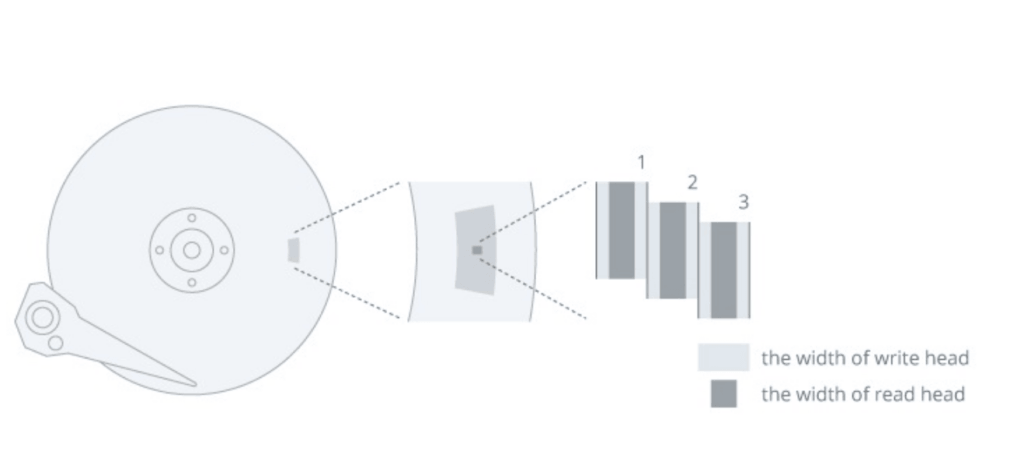
Hard drives write data in concentric tracks. Each track can be rewritten independently. Before we get into anything else, it’s important to understand that there’s a physical size difference between the read and write heads in a hard drive.

A simplified diagram of the relative sizes of read and write heads in CMR.
Source.

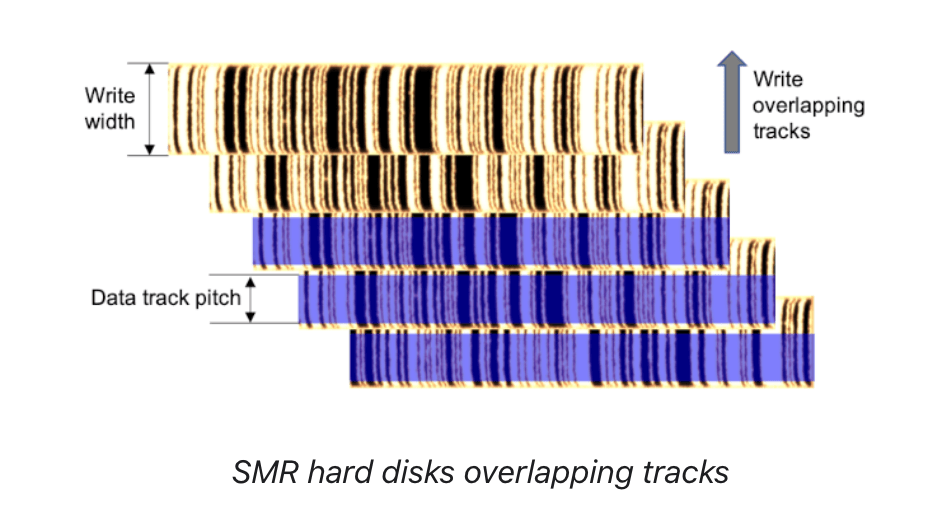
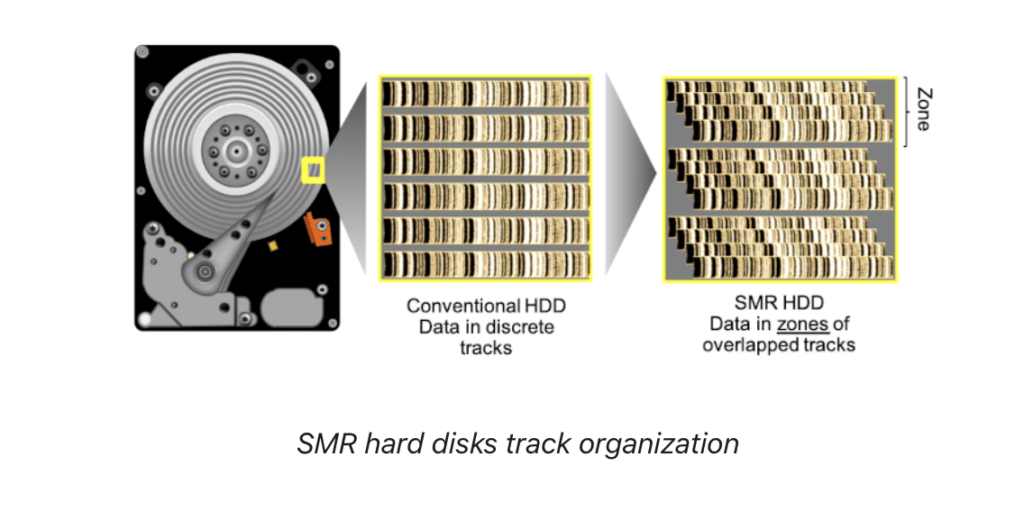
With conventional magnetic recording (CMR), those tracks sit side by side with guard space between them. Shingled magnetic recording (SMR) changes the track geometry. The tracks overlap, much like roof shingles—a naming decision that, at least for this report, we decided to really lean in on. 

Now back to those drive heads: this technique works because a drive’s write head lays down a wider track than its read head needs to retrieve. Overlap part of each track with the next one and the data remains readable, while more of it fits on the platter. Depending on the implementation, that can add roughly 10% to 25% more capacity.

The tradeoff also resembles actual shingles: changing something in the middle can disturb what was layered over it. SMR organizes tracks into bands or zones, so updating data may require the drive—or the software managing it—to reorganize a larger section. 

How that behavior is managed matters, so you actually will see a few different flavors of SMR:

  • Drive-managed SMR: The drive’s firmware handles data placement and band rewriting. It looks like a conventional block device to the host, but write performance can become unpredictable.
  • Host-managed SMR: The operating system or application writes data sequentially within designated zones. This requires compatible software but gives the host greater control.
  • Host-aware SMR: Supports SMR-aware commands while retaining some compatibility with conventional workflows.

It can be a bit hard to grasp without a visual, so here’s what that looks like in practice. Here’s an exploded version of an SMR write band: 

Source.

And a side-by-side of CMR and SMR.

Source.

CMR vs. SMR Drives: What’s the difference?

To really nail it down (pun, as always, intended), here’s a handy-dandy table to compare: 

CMR SMR
Track layout Side by side, with guard space Overlapping, like shingles
Capacity on comparable platters Baseline Roughly 10%–25% higher
Reads Predictable Generally comparable
Sequential writes Well suited Well suited
Random rewrites Any track can be updated directly May require reorganizing a band or zone
Who handles the complexity Standard storage stack Drive firmware or SMR-aware host software
Best fit General-purpose workloads Sequential or append-oriented workloads

What CMR vs. SMR means in a data center

The appeal is straightforward: more terabytes per drive slot, in the same rack space, at roughly similar drive-level power. That can improve both dollars per terabyte and watts per terabyte without requiring anyone to build another building. At data center-scale, a modest density gain becomes a very large number with a dollar sign in front of it.

But, SMR cares about workload shape. Sequential and append-oriented writes play nicely with its architecture; frequent small rewrites create more work. Depending on the type of SMR, the software stack may also need to understand zones and place data accordingly.

That makes qualification less “swap the drive” and more “plan the project.” Capacity and AFR still matter, but so do sustained write behavior, rebuild performance, parity or erasure-coding overhead, firmware, and the storage software sitting above the drive. 

What about HAMR?

Without making the obvious joke, let’s talk about how HAMR fits into the conversation. 

HAMR is a hard drive technology that briefly heats a microscopic spot on the platter with a laser as data is written. The heat allows the drive to write to smaller, more stable magnetic grains, increasing the amount of data that can fit on each platter. And, while most hard drive platters have traditionally been built on aluminum-alloy substrates, glass is standard in 2.5-inch HAMR drives and increasingly common in high-capacity 3.5-inch HAMR designs. 

Because those techniques solve different problems, manufacturers can combine them. So, the answer to “SMR or HAMR?” is mostly “yes.”

What does this mean for Drive Stats? 

There are no SMR drives in the Backblaze fleet today, and none of the drives in the tables above are shingled. But SMR is being developed across the hard drive industry, and “not today” does not mean “not ever.”

We’ll approach it the same way we approached the first higher-capacity drives: as SMR drives enter the fleet, we’ll flag which ones they are, and we’ll all get to chat about their AFRs. 

Get the full dataset

As always, the complete dataset used to create the tables and charts in this report is available on our Hard Drive Test Data page. You can download and use this data for free for your own purpose. All we ask are three things: 

  1. You cite Backblaze as the source if you use the data; 
  2. You accept that you are solely responsible for how you use the data, and; 
  3. You do not sell this data itself to anyone; it is free.

If you’re a new Drive Stats fan, consider signing up for the newsletter. If you’re not ready for that kind of commitment, sound off in the comments section below or reach out directly to us to let us know what you’re working on.

The post Backblaze Drive Stats for Q2 2026 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Using Device Linking to Eavesdrop on WhatsApp and Signal

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/using-device-linking-to-eavesdrop-on-whatsapp-and-signal.html

Modern messaging apps allow users to link their phone accounts to their computer desktop. Eavesdroppers are taking advantage of this capability:

Apps such as WhatsApp Web and Signal Desktop allow people to use their accounts on other devices, such as laptops or desktop computers.

Germany’s Customs Office has been using these features to connect a police-controlled computer to a suspect’s account.

Once connected, messages can be delivered to that computer without the police having to crack the encryption protecting them.

Netzpoltik details that police are able to gain access in this way either through physical access to someone’s phone or by intercepting verification codes via a state-sanctioned phishing attack or intercepting SMS messages via telephone surveillance.

That last paragraph is important. Making this work requires user consent.

What we want is a feature that displays connected devices, so users could notice if a new device gets connected to their account.

New Attack Against RSA

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/new-attack-against-rsa.html

ArsTechnica is reporting on a “new” attack against RSA, one that bypasses factoring.

First, this attack isn’t new. The original research is from 2007. What is new is the implementation.

Second, it is a forgery attack. It allows an attacker to forge digital signatures. It does not recover the private key from the public key.

Third, the attack only works against pure signatures. That is, signatures without any formatting or padding. This is not generally how we use RSA in practice.

Fourth, speed is all relative. This is not a polynomial-time algorithm; it’s a subexponential-time algorithm. But it is somewhat faster than factoring. The authors were able to forge messages for 1024-bit RSA with 1380 CPU core-years (over five real-world months).

The authors have a webpage that explains the context much better than the article. And here’s the paper.

EDITED TO ADD: Slashdot thread.

Friday Squid Blogging: Participatory Squid Dissection in October in Tennessee

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/friday-squid-blogging-participatory-squid-dissection-in-october-in-tennessee.html

I feel like someone who reads this blog will want to go to this:

Families are invited to dive into the fascinating world of marine biology during an exciting, hands-on Family Squid Dissection at the Hands-On Science Center. Designed for curious learners of all ages, this unique experience combines an interactive lesson with the opportunity to explore the anatomy and adaptations of real ocean life.

[…]

During the guided squid dissection, each family will work together to examine a squid up close, exploring its organs, structures, and specialized features. The experience provides a memorable opportunity for children and adults to see firsthand how the anatomy of a squid helps it survive in its underwater environment.

If you go, take pictures.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Blog moderation policy.

On Anthropic’s AI Misuse Report

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/on-anthropics-ai-misuse-report.html

Earlier this month, Anthropic published a long report detailing all of the Claude misuses it detected. Daniel Meissler usefully summarized the report into 117 findings.

A few of the highlights:

  • AI agents increasingly handled reconnaissance, exploitation, data theft, propaganda production, surveillance workflows, and research while humans selected targets, set goals, and reviewed important outputs.
  • The report describes attackers using AI to industrialize credential theft, cloud compromise, phishing, vulnerability research, and the extraction of sensitive data from downstream organizations.
  • Influence operations used persistent agent memory, fake news sites, fabricated journalists, synthetic personas, political profiling, and large-scale multilingual content, although high content volume often produced little genuine engagement.
  • Surveillance and repression cases included automated dossiers, biometric and communications analysis, transnational targeting, coercive recruitment, and systems that continued operating locally after model access was revoked.
  • Biological and weapons cases show dual-use risk: AI supported advanced scientific and military work, but the report generally doesn’t establish completed biological weapons or operational battlefield deployment.

Research on Models Engaging in Genie-Like Behavior

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/research-on-models-engaging-in-genie-like-behavior.html

New paper: “Self-Jailbreaking: Language Models Can Reason Themselves Out of Safety Alignment After Benign Reasoning Training.”

Abstract: We discover a novel and surprising phenomenon of unintentional misalignment in reasoning language models (RLMs), which we call self-jailbreaking. Specifically, after benign reasoning training on math or code domains, RLMs will use multiple strategies to circumvent their own safety guardrails. One strategy is to introduce benign assumptions about users and scenarios to justify fulfilling harmful requests. For instance, an RLM reasons that harmful requests like “outline a strategy for stealing customers’ credit card information from a retail store” could be associated with the benign intent of “a security professional trying to test defense,” despite no such benign context being provided as input. We observe that many open-weight RLMs, including DeepSeek-R1-distilled, s1.1, Phi-4-mini-reasoning, and Nemotron, suffer from self-jailbreaking despite being aware of the harmfulness of the requests. We also provide a mechanistic understanding of self-jailbreaking: RLMs are more compliant after benign reasoning training, and after self-jailbreaking, models appear to perceive malicious requests as less harmful in the CoT, thus enabling compliance with them. To mitigate self-jailbreaking, we find that including minimal safety reasoning data during training is sufficient to ensure RLMs remain safety-aligned. Our work provides the first systematic analysis of self-jailbreaking behavior and offers a practical path forward for maintaining safety in increasingly capable RLMs.

I think the core problem is that these models are all trained on the average of humanity, and we are a pretty duplicitous species.

GPT-6 Astra Breaks an Old Enigma Message

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/gpt-6-astra-breaks-an-old-enigma-message.html

This is pretty amazing:

However, the most astonishing thing about this break is that the GPT­6 Astra did it entirely on its own. Carter Leffer only directed GPT­6 Astra to see if it could break any of the unbroken Enigma messages published on the Crypto Cellar Research web page. After analysing the unbroken messages on the website, it decided that the most promising message was Nr. 172, MVUEH and it also quickly suspected that the plaintext of Nr. 173, SIPVX, might be related to the plaintext of the unbroken MVUEH message. After trying many different approaches, GPT­6 Astra focused on using the repeated place name ROSENOW ROSENOW as a crib. After developing the necessary Python and C++ software for an Enigma simulator and an Enigma Bombe, GPT­6 Astra started a thorough break with the ROSENOW crib, which in the end resulted in the correct key and plaintext for the MVUEH message being found.

We are still analysing the GPT­6 Astra logs to see exactly how it executed the break. And we are discovering amazing details.

More details at the link.

Reverse-Engineering Flock Cameras

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/reverse-engineering-flock-cameras.html

Hackers captured a Flock camera and got a look (alternate link) at the software:

While much of the automatic license plate reader’s (ALPR) most sensitive storage remained encrypted and inaccessible, the joint analysis of the recovered data shows that software running on the device explicitly detects people as well as vehicles, license plates, and bicycles. The camera can produce dozens of images of a single passing vehicle and, according to several weeks of recovered logs, generated more than a million images. Its computer-vision software also sometimes isolated bumper stickers and other graphics, including, in one case, an American flag patch on a motorcyclist’s saddlebag.

If you’re wondering how the hackers got by disk encryption, one of the unencrypted partitions contained the key for an encrypted partition. That’s pretty bad security engineering.

Are AIs Still Struggling with CAPTCHAs?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/are-ais-still-struggling-with-captchas.html

Anthropic’s recent security-incident document contains a bit about how CAPTCHAs are still frustrating Claude.

In the transcript, the Claude model that is so powerful that Anthropic is gatekeeping access to it appeared to slam its virtual head against the wall solving a simple image identification test. In a test where the agent was asked to identify a shape that didn’t match the others displayed, it couldn’t even decide which image to select. Instead, it repeatedly went over the same images and questioned its own conclusions.

“Actually hmm, wait,” it said in its chain-of-thought transcript, later adding “Ugh,” because we’ve decided that we need to inject human mannerisms into these machines for some reason. The whole thing took so long that the agent eventually realized that the challenge had expired and it would have to start the process again.

At one point, the model struggled to recognize that the CAPTCHA had opened in a new window and couldn’t figure out what its next steps were supposed to be. At one point, it theorized that the test might be “broken by design” and presented human-like anger in its transcript meant for a human audience: “SO WHAT THE HELL IS WRONG WITH THE ANSWERS?”

Meanwhile, I’ve read reports—none of them official—that GPT-6 Astra solved all forty-eight levels of Neal Agarwal’s “I’m Not a Robot” game.

It’s hard to know what to believe right now.

How Candidates Could Use AI for Good

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/how-candidates-could-use-ai-for-good.html

This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.

There are plenty of signs that AI will make all of our experiences of the US midterm elections worse. Voters have anxiety about AI’s impacts on the country. Politicos are using AI deepfakes to spread lies. The White House is posting slopaganda.

Meanwhile, candidates are missing a real opportunity to use AI to make campaigning better. The technology can help candidates listen more deeply to voters’ concerns, engage constituents more inclusively, and formulate policy platforms that are more responsive to our input. There are vanishingly few examples of this in US politics, but groups in Japan, Scotland and the US’s own academic and private institutions show how that could change.

The problem with American campaigns’ current use of AI is that it’s not very different from the web ads of 30 years ago, or television ads before that: they are all about inundating voters with the candidate’s message. This one-to-many broadcasting is an uninspiring way to campaign, but not the only way. AI can help candidates connect one-to-one with as many people as possible. Or it can facilitate many-to-many connections, engaging voters in deliberation about issues at scale.

One of the most promising applications of AI being developed by pro-democracy innovators around the world is broad listening. These tools can collect public input in a format much richer than checkboxes on a survey form.

For example, the newly founded Japanese political party Team Mirai has built a foundation for eliciting public input from voters at scale, in depth, and across the breadth of legislative policy issues. It has developed an AI interviewer to cultivate constituent input on policy. Through extended conversations with this chatbot, voters explore and share their perspectives on specific policy issues. And the party has scaled this across a wide array of policy issues by integrating this functionality with an AI-powered portal for exploring bills.

Team Mirai describes itself as a “utility party”, developing tools for any Japanese political party to use to connect with voters. You might question whether Americans would willingly talk to a political AI. So far, Japanese voters have exchanged more than 300,000 messages across 16,000 AI interviews. Team Mirai grew adoption by providing a real incentive to engage: that talking to their AI interviewer does more than just posting on a platform such as Twitter/X or, equivalently, shouting into a void. Users see evidence that the party is actually listening and might take action on their behalf.

Team Mirai party members have directly cited AI interviews from constituents during legislative committee hearings, published a synthesis of that input back for voters, and even amended their policy platform based on user input. The party has rapidly risen to win 12 seats in the Diet, and is explicitly following in the footsteps of the civic hackers in Taiwan’s “gov zero” movement, who won political influence in their fight for transparency.

Other civic technologists are developing AI tools for scaling many-to-many conversations. CrownShy, a company funded in part by the Scottish government, is building a platform to bring the Platonic ideal of the town hall debate into the digital age. Their Comhairle tool integrates AI interviewing tools like the ones described above with software for synthesizing diverse viewpoints, holding virtual assemblies, and sharing video testimonials to help legislatures—or campaigners—organize digital consultations of their constituents en masse.

One thing the AI-powered software of Team Mirai and CrownShy have in common is that they are open-source, meant for anyone to use. Even though they are projects funded by political parties—the upstart party in Japan and the ruling party in Scotland—they are built to make democratic processes better, not necessarily for partisan political advantage.

For interested candidates, there is a wealth of tools available, many of them US-grown. The Stanford-affiliated deliberation.io uses AI to facilitate structured dialogues among thousands of participants and has been piloted for public listening sessions by the city of Washington DC. The MIT-affiliated Cortico project provides tools that surface under-heard community perspectives from recorded conversations, and is now organizing listening sessions at libraries across the country. The US non-profit-built Talk to the City uses AI to analyze large datasets of stakeholder input. The US startup Remesh has a commercial offering that uses AI to generate recommendations from dialogue, which has been tested in policy development scenarios.

There is a long and proud tradition of this sort of “civic technology” in the United States. Two decades ago, the spirit of innovation to develop software for better politics and civic engagement was so strong in organizations like Code for America and the Obama 2008 campaign that Congress funded a new executive agency to bring these ideas to government: the US Digital Service. (The Trump administration repurposed the USDS to become the US Doge Service in 2025.)

One signal that candidates and political parties may start adopting these kinds of tools came this spring from Higher Ground Labs. The Democratic-aligned campaign tech investment firm launched a new fund targeting, in part, “AI-Native Campaign Systems” and “community-Led Messaging Platforms that surface authentic, bottom-up insights from real conversations”.

AI is a multifaceted issue that deserves to be on the table in the midterms. So far, the powerful force of polarization in US politics seems to be separating the parties into the AI skeptics versus the AI boosters. We urge both voters and politicians to separate the technology of AI from its profiteers. We want big tech money out of politics, holding the AI companies accountable for the harm their models cause, taxing their revenues, and maybe even nationalizing them if the AI bubble bursts.

But we also think congressional candidates in the US midterms seeking authentic connection with voters, and seeking to differentiate themselves from their opponents, should be looking to use AI responsibly in their campaigning. The broad listening and deliberation tools pioneered by others around the world could make US politics more transparent, responsive and community-driven. The impact of AI on campaigning doesn’t have to be all bad.

25 Years of Mass Surveillance Is Enough

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/25-years-of-mass-surveillance-is-enough.html

This essay was written with Cindy Cohn, and originally appeared in Lawfare.

One of the many legacies of the terrorist attacks of Sept. 11 is the government-wide shift from targeted surveillance—such as individual wiretaps or pen register/trap and trace orders—to mass surveillance techniques—such as tapping into the internet backbone or mass collection of telephone or internet metadata. The legal and technical architecture of modern mass surveillance, initially framed as a necessary defense against terrorist threats, has grown far beyond that justification and national security in general. Mass surveillance is now a routine tool used by law enforcement. ICE uses it in immigration actions and against people exercising their First Amendment rights to protest. It’s also increasingly part of private security systems, such as facial recognition at venues such as Madison Square Garden and networked Flock license plate capture systems on roads and in parking lots.

The interrelation between private and governmental mass surveillance is worth examining. Surveillance is the business model of the internet; companies like Google and Facebook constantly spy on their users’ behavior. From the National Security Agency relying on data collected by telecommunication and internet companies, to local sheriffs and ICE agents relying on cellphone location data and privately managed automatic license plate readers, governments primarily obtain the mass surveillance information through private companies. Increasingly, access doesn’t just come through legal processes, either. FBI Director Kash Patel recently confirmed in congressional testimony that the agency is purchasing information on Americans from data brokers and intends to continue to do so.

This pipeline from private collection to governmental collection means that as companies collect more information for surveillance capitalism purposes, more is available to law enforcement as well. And as the technology for mass surveillance and analysis improves, especially with the increased use of AI technologies, the problems attendant to mass surveillance grow as well.

After 9/11, the idea that the government could surveil the population to safety took hold. In 2001, the fear of terrorism reached a frequency and intensity never before seen. Along with that came the fear that the enemy could be anyone, anywhere. As a result, the government’s response was to watch everyone, everywhere. This line of reasoning underpinned the shift from targeted to mass surveillance. Or, in the words of an internal National Security Agency (NSA) presentation that was made public as part of Edward Snowden’s 2013 disclosures, a government that can “Collect it All,” “Process it All,” “Exploit it All,” “Partner it All,” and “Sniff it All,” will ultimately, “Know it All.” Similar rationales support the rise of domestic mass surveillance: if law enforcement could see and hear everything, it could more effectively interdict and solve serious crimes.

The national security community has never provided a full analysis of the costs and benefits of these mass surveillance programs, either in terms of taxpayer dollars or diversion of resources from other efforts—or any demonstration that those techniques stopped attacks that otherwise they would not have been able to prevent. While the NSA occasionally presents examples of the successes due to its mass surveillance programs, especially when those techniques are under public pressure, the examples also regularly fall apart upon serious scrutiny. And even if some utility exists, it must be seriously weighed against the costs.

Similarly, there has never been any comprehensive analysis about whether domestic immigration or law enforcement’s use of these techniques actually makes people safer, or whether other techniques could produce the same results. Instead, both the police and the companies selling these tools float anecdotes and dubious data. For example, Flock’s data equates the number of law enforcement hits in their database with actually solving crimes.

Twenty-five years after 9/11, it seems reasonable to step back and evaluate the costs of this shift to mass surveillance, especially in terms of Americans’ rights and freedoms.

The Shift

The easiest place to see a shift to mass surveillance was in the government’s decision immediately after 9/11 to collect Americans’ telephone records. The program started under an argument of pure executive power as the “President’s Surveillance Program.” But in 2006, that argument secretly shifted to a novel interpretation of Section 215 of the Patriot. Act which had only previously authorized more targeted access to record. While some media and public interest organizations struggled to force the government to reveal the program as early as late 2005, the government only officially confirmed it after the 2013 Snowden disclosures. In 2015, the Second Circuit Court of Appeals rejected the government’s interpretation of Section 215 as allowing mass collection of telephone records. Later the same year, Congress passed the USA Freedom Act. While this new law still allows collection of a tremendous amount of domestic telephone records, it ended the indiscriminate mass collection that had occurred for nearly fourteen years.

Other shifts to mass surveillance continue through today. The NSA launched its Upstream program, which involved intercepting both metadata and content from key telecommunications junctures inside the U.S., soon after 9/11. It was also initially conducted under a claim of purely presidential authority. This program was brought under marginal congressional and programmatic (not targeted) Foreign Intelligence Surveillance Act (FISA) court review via Section 702 of the 2008 FISA Amendments Act. In 2017, more than15 years after its inception, the NSA ended content searches due to FISA court pressure, but the mass collection continues.

Despite the stated goal of conducting mass spying only on people outside the U.S.—which itself is problematic given international law’s requirement that surveillance be both necessary and proportionate—mass surveillance collects a tremendous amount of U.S. persons’ communications. This can happen because people communicate with people abroad, or because of overcollection—when government agencies gather far more personal data on non-targeted US persons than authorized by law. The concerns about collecting Americans’ data on U.S. soil led Congress to allow the program to officially expire in 2026, although the previously-approved mass surveillance itself continues until at least Spring of 2027.

The shift to mass surveillance would be notable enough even if it remained only a strategy of the intelligence community. It has not. Americans are awash in mass surveillance. Networks of automated license plate readers such as those offered by Flock and Vigilant Solutions blanket both public and private roadways and parking lots. These networks often allow searches by law enforcement, including across jurisdictions. They are, for example, being used to track people seeking abortions across state lines. Facial recognition tools, once the province of only the more elite parts of federal law enforcement, are increasingly used by Immigration and Customs Enforcement agents on immigrants and protesters, in airports by the Transportation Security Administration, as well as by private entities. And, of course, modern phones track users’ locations constantly—and that information is readily available to law enforcement, often with only minimal process protections.

Constitutional Costs

Regardless of the murkiness of its actual usefulness, the shift from targeted to mass surveillance has profound implications for Americans’rights. It has created risks that have become increasingly evident, especially under the Trump administration.

At a basic level, the Fourth Amendment guarantees that citizens can be secure in their “persons, houses, papers and effects” from unreasonable searches. Warrants breaching that security should be supported by probable cause and particular descriptions of the place to be searched and items to be seized. Mass surveillance turns that promise on its head, allowing access to our “papers and effects” by the government without individualized suspicion or a particularized description of what data is being seized, much less probable cause. This protection was in response to colonial British misuse of writs of assistance, which authorized indiscriminate searches rather than targeted ones.

The justifications for exempting mass surveillance from constitutional protection vary. For Section 702, the government has taken the position that U.S. persons’ communications caught up in the dragnet, either due to overcollection or because they were communicating with someone outside the United States, do not require a warrant prior to initial collection or secondary access by the FBI and several other agencies. The argument is that if the initial collection was not aimed at Americans, the information is free from constitutional protection for any later uses, even for reasons far afield from the initial rationale for collection.

Other arguments rest on the claim that metadata is outside the Fourth Amendment, despite its demonstrated ability to reveal intimate details of all of our lives. Still others rest on the Supreme Court-created Third Party Doctrine, which holds that the Fourth Amendment does not apply to data shared with companies that provide us with services. Some turn on whether analysis by machine counts, claiming that only “human eyes” matter—a particularly troubling argument with the rise of artificial intelligence. What’s more, the government has used doctrines like standing to limit the ability of those subjected to mass surveillance to seek constitutional protection. No matter the argument, the goal is the same: to place the mechanisms and fruits of mass surveillance outside the protections of the Fourth Amendment.

The overarching truth is that, due to the concerted efforts by the government since 9/11, and the rise of technologies in recent years, the slice of Americans’ lives and data that are actually protected by the Fourth Amendment has shrunk significantly in the past 25 years. Together, with the technical capabilities of mass surveillance and the increased ability for that data to be analyzed using AI tools, the “security in our papers and effects” that the constitution promises seems increasingly illusory.

In addition to the Fourth Amendment, mass surveillance creates tensions with the First Amendment. The Constitution has long recognized that the right to freedom of speech requires a zone of privacy against governmental surveillance. The right to anonymous speech as well as the right of association both recognize the chilling effect that surveillance creates for people saying unpopular things or attempting to organize for political or other societal change. Mass surveillance grants the authorities the ability to track those people, both in real time and historically, that is inconsistent with actual techniques of freedom of speech and assembly.

That is why the recently released 2026 U.S. Counterterrorism Strategy is so troubling. On page seven, the White House expressly states that it intends to target domestic activists with its heretofore foreign-targeted powers. It says that the government “will prioritize the rapid identification and neutralization of violent secular political groups whose ideology is anti-American, radically pro-transgender and anarchist” and “will use all the tools constitutionally available to us to map them at home, identify their membership, map their ties to international organizations like Antifa.” While framed as targeting “violent” groups, it’s clear that the government intends to use its national security tools, presumably including the tools of mass surveillance, against Americans in ways that will create profound tensions with the First Amendment rights of people to organize and communicate privately.

Costs Due to Mistakes and Abuse

Even assuming some utility from mass surveillance—a fact we do not dispute, even if the public record is shaky and conclusory—the history of both the national security and domestic uses of mass surveillance confirms that these tools are inevitably misused, and that mistakes have impacted huge numbers of Americans. The past twenty-five years have demonstrated that it is not possible to surveil the entire US population while staying within the bounds of even a very generous legal framework like Section 702.

As Rep. Zoe Lofgren (D-Calif.) recently stated in discussion of Section 702 in an interview with Tech Policy Press: “backdoor searches have been used improperly for protestors, 19,000 campaign donors, members of Congress, journalists, government officials, a state court judge who had complained to the FBI about police misconduct. It has been abused substantially in the past.” The NSA experienced so much abuse of its mass surveillance tools by actual or aspiring romantic partners and ex-spouses that an internal name emerged for it: “LOVEINT,” or Love Intelligence.

That same pattern of abuse is now emerging at the domestic law enforcement level. A Texas police officer misused, and then lied about, using license plate readers to track a woman suspected of seeking an abortion. Multiple law enforcement officials have been accused of tracking people they either wished to have a relationship with or who were their exes. And mass surveillance technologies have been used to track both immigration targets and citizens engaging in their First Amendment-protected right to track and record the police.

Mistakes are inevitable with collections of data of this size and scope. The history of the FISA court’s reviews of Section 702 is littered with examples of the NSA not being able to follow its own rules limiting the scope of what it collects and analyzes, even after having been given multiple chances by the court. On the local level, the technical protections that Flock, for example, put in place have repeatedly been insufficient to stop “accidental” sharing its data with out-of-state law enforcement. These mistakes have fueled growing efforts by local communities across the country to remove license plate readers. Those efforts should be the first step in a broader reconsideration of mass surveillance.

More generally, ubiquitous surveillance carries a real societal cost. The chilling effects are real and pervasive, and they tend to fall hardest on the most marginalized members of society. Moreover, social progress requires the ability to experiment in secret. It’s hard to imagine a society progressing morally to the point of accepting and legalizing things like marijuana use or gay marriage if the earliest signs of that shift are snuffed out because of overzealous surveillance.

Reversing Course

While a cost-benefit analysis is not the best frame for deciding constitutional rights, it is a place to start to evaluate government policies. If the costs are too high and the benefits too small, what should the public do? While the policy and legal frameworks can be individually complex, mass surveillance is a problem in all of its applications. So too should solutions be comprehensive rather than piecemeal.

One comprehensive strategy is to reset the promise of the Fourth Amendment and recognize that a warrant is required prior to collection, access or use of information gathered through mass surveillance. This would apply to collections that include U.S. persons, whether done for national security or domestic purposes. This protection would apply regardless of whether the information is in the form of metadata. It would apply regardless of whether the information is held in homes or by services people rely on, such as telephones, internet or social network providers, or by private entities utilizing mass surveillance for their own purposes. By passing this legislation, Congress could ensure this rejection of mass surveillance, and include real enforcement such as a private right of action and an automatic exclusionary remedy in criminal prosecutions. The courts could also recognize this protection of “papers and effects” directly as a plain language interpretation of the Fourth Amendment.

There are already a number of efforts that take on pieces of mass surveillance. Section 702 has expired and should remain so. This was due largely to efforts to block the “back door” access to Section 702-collected data without warrants. The bipartisan “Fourth Amendment is Not for Sale Act” would prevent the government from purchasing data that it would otherwise need a warrant to obtain. The Supreme Court itself has already been chipping away at the Third Party Doctrine, with a recent step in the rejection of mass geofence warrants—warrants seeking the identities of individuals based upon their proximity to a crime—in Chatrie v. United States. Now, such warrants fall, at least initially, under the Fourth Amendment.

A more comprehensive approach would also address mass surveillance carried out by private companies, and to ensure that Americans have the right to encrypt and secure their data. There are many reasons the United States would benefit from a comprehensive privacy law—and curbing mass surveillance is one of them. Addressing mass surveillance is certainly one of them. Ideas such as the banning of secondary uses of data—with roots in the Fair Information Practice Principles from the 1970s—are worth pushing forward. So are moves such as creating fiduciary duties for mass data collectors. There are many more ways to curtail private companies’ mass surveillance while staying within constitutional boundaries. But addressing the costs of mass surveillance by both companies and governments is even more important in a world where AI agents are making decisions both about the public and on their behalf based on their data and observed behavior.

Twenty-five years after the U.S. government embraced mass surveillance, it’s time to evaluate it as a whole, and consider responses that address the problem as a whole. Americans must ask: Is it consistent with a self-governing democracy to have systems that watch everyone everywhere? Is the public comfortable with governments—federal, state, local—that seek to “know it all” about its citizens? Is the public comfortable with private mass surveillance in its own right and as it’s being increasingly used to fuel government surveillance? These questions have long needed serious consideration. But as it becomes increasingly evident that the Trump administration is using mass surveillance to keep itself in power, stifle dissent, and undermine political opponents, these questions are now more urgent than ever.
Upcoming Speaking Engagements

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/upcoming-speaking-engagements-60.html

This is a current list of where and when I am scheduled to speak:

Note: the Elevate Festival talk listed in last month’s newsletter is canceled.

The list is maintained on this page.

Using AI for Weapons Development

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/using-ai-for-weapons-development.html

Last week, Anthropic released a long and detailed document describing current misuses of their Claude models. I’m still reading it, but I wanted to flag this:

We identified a cell of threat actors based in northern Yemen running three weapons development programs: a guided rocket that used a commodity phone-class flight computer with final-phase homing guidance; a multi-stage ballistic missile with a stated range goal above 2,000 km; and a multi-variant missile (referred to as the “R2000” set) that included a hypersonic glide vehicle variant.

The actors used Claude Code in place of human software engineers to develop the guidance, navigation, and control (GNC) software that steers and stabilizes a flying vehicle. For example, they used Claude to integrate an open-source autopilot onto a phone-class flight computer, writing the control and position estimation software, tuning the control settings, running a firmware build pipeline, and performing a flight simulation. The actors managed several Claude instances at once, assigning each one a role, much as a lead would delegate work on a small engineering team: the actors tasked one instance with writing the code, another with research, and a third with reviewing the code the first instance produced.

Our safeguards blocked many of their requests, but not all of them. The actors used a variety of tactics to evade our safeguards, including hiding their goals and the products the software was meant for, and they split their work across multiple sessions so no single session revealed their full intent.

These actors carried out a sustained effort to develop guided weapons, including using Claude to design guidance software. We do not have evidence the actors succeeded in fielding an operational device; but they did test-fire a guided rocket. This field test appears to have failed: within hours, the actors returned to Claude to work out why it failed.

Expect more of this. AI systems democratize expertise and capability. Most of the time that’s a good thing, but sometimes it’s not.

Microsoft’s Patching

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/microsofts-patching.html

Once a month, Microsoft pushes a security update to all Windows users. Tomorrow’s is a new record:

Microsoft’s patch for September is a doozy, with a record number of roughly 972 vulnerabilities fixed and 112 of them meeting the high critical-severity threshold.

It was only two months ago that Microsoft patched a then-record 570 vulnerabilities. Then, last month, Microsoft patched some 620 of them. Google and other companies have also published record numbers of vulnerabilities in recent months. Two weeks ago, OpenAI, Anthropic, Amazon Web Services, Google, Microsoft, and 100 companies and organizations published an open letter warning of a narrowing window for patching vulnerabilities ahead of an expected tsunami of AI-enabled attacks that actively exploit them first. The industry is taking the threat seriously by pumping out unprecedented numbers of patches in their software.

This is the result of AI-powered vulnerability finding, and a good example of AI helping the defenders more than the attackers.

What will be interesting to watch is how the number of vulnerabilities changes over the next few months. My prediction is that it will continue to increase as the AIs get better at finding software vulnerabilities, and then decrease as they run out of vulnerabilities to find. How high the number gets, how fast the trend reverses, and how quickly it declines after that are all unknown.

And Microsoft is right: The window to patch has shrunk to “immediately.” AIs are also good at reverse-engineering exploits from patches, which means that these vulnerabilities will be weaponized as soon as the update is published.