Tag Archives: Uncategorized

New iOS Security Feature Makes It Harder for Police to Unlock Seized Phones

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/new-ios-security-feature-makes-it-harder-for-police-to-unlock-seized-phones.html

Everybody is reporting about a new security iPhone security feature with iOS 18: if the phone hasn’t been used for a few days, it automatically goes into its “Before First Unlock” state and has to be rebooted.

This is a really good security feature. But various police departments don’t like it, because it makes it harder for them to unlock suspects’ phones.

Amazon Q Developer plugins now generally available for the AWS Management Console

Post Syndicated from Shardul Vaidya original https://aws.amazon.com/blogs/devops/amazon-q-developer-plugins-now-generally-available/

Today, Amazon Web Services (AWS) announced the launch and general availability of Amazon Q Developer plugins for Datadog and Wiz in the AWS Management Console. When chatting with Amazon Q in the console, customers can access a subset of information from Datadog and Wiz services using natural language. Ask questions like @datadog do I have any active alerts? or @wiz what are my top 3 security issues today? to swiftly identify and fix problems without leaving the console.

Engineers and IT professionals can struggle with tool sprawl throughout an application’s operational lifecycle. Amazon Q Developer’s third-party plugin system works towards creating a single pane of glass for all your SaaS solutions.

In this post, we’ll explore:

  • How Q Developer plugins work
  • How to use these plugins to:
    • Understand the state of your infrastructure
    • Query and brainstorm on present issues
    • Generate code and CLI commands to use third-party systems
  • How to get started

Our goal is for you to gain a comprehensive understanding of how the third-party plugins will improve your operational productivity.

How do Q Developer plugins work

Amazon Q in the console uses the prefix you provide to select which plugin to query. This provides additional context on your request and the state of your infrastructure. Key processes include:

  • Intent recognition: Amazon Q Developer interprets your chat request’s intent. It searches through relevant APIs it can invoke and selects the correct workflow to get more context.
  • API invocation: Amazon Q Developer then calls the appropriate third-party APIs to gather relevant information. Neither the AWS context included in the chat nor any information from your prompt is passed to the third-party.
  • Response Generation: After obtaining the enriched context and original prompt, Amazon Q Developer composes a complete prompt. Amazon Q uses this to generate the best response.
  • Guardrails: The system checks the response against Amazon Q Developer guardrails to ensure it follows best practices.

This system enables Amazon Q Developer to, understand intent, request additional information, and provide rich assistance across your infrastructure and application operations.

Let’s see how each of the third-party plugins can help in a set of real-world use-cases.

Amazon Q Developer plugin for Datadog

Datadog, an AWS Advanced Technology Partner and observability and security platform for cloud applications, provides AWS customers with unified, real-time observability and security across their entire technology stack. Datadog unifies all of your telemetry in one place, so teams can troubleshoot, optimize, and secure resources at scale. If you use Datadog to
monitor your AWS infrastructure and applications, you can query a subset of information from Datadog without leaving the AWS console by prefixing your Amazon Q queries with @datadog.

Learn to use Datadog in your workloads

You can ask about how Datadog features work with certain AWS services, by asking questions like @datadog how do I use APM on my EC2 instance?
Gif of Q Developer plugin for Datadog answering a question about how to use APM on EC2

Retrieve and summarize cases and monitors

You can ask about specific cases, monitors, or specify properties of a case to get more information about it and include it in your conversation by asking questions like @datadog list my cases. With a follow up to quickly get a summary of your top cases, @datadog summarize my top cases

Gif of Q Developer plugin for Datadog answering a question about all the current cases in the connected instance of datadogGif of Q Developer plugin for Datadog answering a question summarizing the top cases in the connected instance of datadog

Check and list monitors in alarm

You can ask about specific application monitors as well, including which monitors are in alarm, Amazon Q Developer also allows follow-up questions about which alarmed monitors. You can start with a question like, @datadog list my current monitors

Gif of Q Developer plugin for Datadog listing out all the monitors in the connected instance of datadogGif of Q Developer plugin for Datadog stating that there are currently no monitors in an alarmed state in the connected instance of Datadog

And then follow it up with a question like, @datadog List some of the resources that are triggering the alarm

Amazon Q Developer plugin for Wiz

With Wiz, organizations can democratize security across the development lifecycle, empowering them to build fast and securely. As an AWS Security Competency Partner, Wiz is committed to effectively reducing risk for AWS customers by seamlessly integrating into AWS services. If you use Wiz to monitor your AWS infrastructure and applications, then you can query Wiz without leaving the console by prefixing your queries with @wiz.

View issues with critical severity

You can ask Q Developer to retrieve the specifics of your issues in Wiz, the plugin can currently return up to 10 issues and you can focus on a specific severity with a question like, @wiz list the issues with critical severity
With that response, we can also ask it to find the top issues, with a follow-up question like, @wiz can you specify the top 5?
Gif of Q Developer plugin for Wiz showing how many critical severity issues detected by the connected instance of Wiz

Find your critical resources

Wiz defines the security posture of your AWS resources based on their configuration and how many critical issues that are associated with them. Amazon Q Developer can ask Wiz which are the least secure resources with a question like, @wiz what are the critical resources in my AWS environment?
Gif of Q Developer plugin for Wiz listing out all the critical resources noted by the connected Wiz instance

List issues based on certain properties

Wiz tracks security issues that exist in your AWS account and you can ask Amazon Q Developer to list issues based on date, status, severity or type, with questions like, @wiz what issues are due next?
Gif of Q Developer plugin for Wiz listing the next few issues listed in the connected Wiz instance

Assess issues with security vulnerabilities

Wiz tracks external vulnerabilities and exposures that can potentially pose a security threat associated with your current resources and issues. Amazon Q Developer can ask Wiz which are the pertinent vulnerabilities with a question like, @wiz what are my issues that have been created in the last 7 days?
Gif of Q Developer plugin for Wiz listing the issues that Wiz lists are newest

Getting Started

To enable third-party Plugin capability in the Amazon Q Developer console:

  1. To use third-party plugins, subscribe to Amazon Q Developer Pro Tier if you don’t already have it. This activates plugins at an organizational level.
  2. If you don’t already have a Amazon Q Administrator Role/User, create one using either the AmazonQFullAccess / AmazonQDeveloperAccess managed policies, or follow the instructions in the Q Developer user guide for security and IAM permissions.
  3. Configure the plugins – To activate the plugins, you must configure their credentials to authenticate into the third-party system. This is possible through a new tab called “Plugins” in the Amazon Q Developer dashboard. The plugins require credentials from the third parties to authenticate and call APIs specific to your accounts. They’re stored in your AWS account in Secrets Manager.
    Image of the Amazon Q Developer dashboard in the AWS Management Console showing the new Plugin sidebar item

    1. Datadog – Follow the instructions in the Datadog API documentation to create a Datadog API key and copy over the Site URL, API Key, and application key to authorize Q Developer with your instance of Datadog.
      Image of the Amazon Q Developer dashboard showing the configuration screen for the Datadog plugin requesting the Site URL, API key, and application key for the instance of Datadog you wish to connect Image of the Datadog settings UI showing where to get the Site URL, API key, and application key
    2. Wiz – Follow the instructions in the Wiz Service account documentation to create a client ID, the client secret generated by wiz, and then retrieve the Wiz API endpoint URL to connect Amazon Q Developer to Wiz.
      Image of the Amazon Q Developer dashboard showing the configuration screen for the Wiz plugin; requesting the client ID, client secret, and the Wiz API endpoint URL for the instance you wish to connectImage of the Wiz UI settings UI showing where to get the client ID, client secret, and the API endpoint URL
  4. Query the new plugins – With the @datadog and @wiz prefixes, you can ask a wide variety of questions and get operational assistance leveraging from third-party SaaS products. This allows you to integrate data from all sources with lower overhead and friction.
  5. Iterate and refine – Try rephrasing or explicitly including more context about the request by mentioning dates or issue severity. Providing more relevant information helps Amazon Q Developer better understand your request.

For best results with third-party plugins, understand what you’re looking for and use terminology specfic to the third-party. Avoid overly broad queries to guide Amazon Q Developer effectively.

Conclusion

In this post, we introduced Amazon Q Developer’s third-party plugins in chat via the @datadog and @wiz prefixes highlighting the benefits of using plugins when trying to leverage generative AI across multiple services. By allowing Q Developer to understand and analyze the state of your infrastructure across services, third-party plugins unlock new boundaries for operational productivity gains.

Shardul Vaidya is a Worldwide Partner Solutions Architect with AWS, focused on helping partners and customers build and effectively use Generative AI powered developer experiences. Shardul joined AWS in 2020 as part of their early career talent Solutions Architect team and worked with over a hundred modernization and DevOps partners across the world. Outside of work, he’s a music lover and collects records.

Criminals Exploiting FBI Emergency Data Requests

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/criminals-exploiting-fbi-emergency-data-requests.html

I’ve been writing about the problem with lawful-access backdoors in encryption for decades now: that as soon as you create a mechanism for law enforcement to bypass encryption, the bad guys will use it too.

Turns out the same thing is true for non-technical backdoors:

The advisory said that the cybercriminals were successful in masquerading as law enforcement by using compromised police accounts to send emails to companies requesting user data. In some cases, the requests cited false threats, like claims of human trafficking and, in one case, that an individual would “suffer greatly or die” unless the company in question returns the requested information.

The FBI said the compromised access to law enforcement accounts allowed the hackers to generate legitimate-looking subpoenas that resulted in companies turning over usernames, emails, phone numbers, and other private information about their users.

Peek inside your AWS CloudFormation Deployments with timeline view

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/peek-inside-your-aws-cloudformation-deployments-with-timeline-view/

AWS CloudFormation makes it easy to model and provision your cloud application infrastructure as code. CloudFormation templates can be written directly in JSON or YAML, or they can be generated by tools like the AWS Cloud Development Kit (CDK). These templates are submitted to the CloudFormation service and the resources are deployed together as stacks, in dependency order. Stack events can be viewed in a tabular format in the console, which provides fine-grained details about each event. And now there is a new feature that offers a more visually intuitive view of the events called the deployment timeline view, which provides a visualization of the sequence of actions CloudFormation took in a stack operation. This visual timeline shows you the exact order in which resources are provisioned, dependencies between resources, provisioning times, and likely root causes for any deployment failures. It complements the existing tabular stack events view by giving you additional context and visibility into what happens behind the scenes during deployments.

CloudFormation deployment timeline view feature overview

Figure 1: CloudFormation deployment timeline view feature overview

How It Works

To use the new deployment timeline view, simply initiate a stack create, update, or delete operation. In the AWS CloudFormation Console, choose the Events tab, then click the Timeline view tab next to Table View. As CloudFormation begins provisioning the resources defined in your template, you’ll see each resource operation appear as a bar in the timeline view. The resources are organized in a vertical stack, chronologically ordered with the most recent resource operation at the top. Each resource action is visualized horizontally, segmented by different color bars for each resource action:

CloudFormation deployment timeline view color bars for each resource action

In dark mode, in-progress rollback and completed rollback switch colors.

You can hover over any bar to see additional details like the full resource name and the start/end times of the resource action. If a deployment fails, CloudFormation will highlight the resource operation that was the likely root cause node in a red-and-white striped bar, which you can hover over to see the specific failure reason.

Creating a simple stack

Create a simple stack using CloudFormation Console. You will initiate a deployment and then explore the visual timeline view.

1. From the CloudFormation console, click Create stack and then choose with new resources.

CloudFormation’s create stack console button.

Figure 2: CloudFormation’s create stack console button 

2. In the Create stack wizard, click Choose an existing template and then choose Upload a template file. Click Choose file to select and upload the template file of the stack to deploy. In this blog you will use the template available here. Download the template or you can use your own template. If you decide to use your own template, it will result in a different deployment timeline view.

CloudFormation’s create stack console wizardFigure 3: CloudFormation’s create stack console wizard

The application stack includes the following key resources: Amazon EC2 instance (AWS::EC2::Instance), an Amazon VPC (AWS::EC2::VPC) and related VPC resources like subnets (AWS::EC2::Subnet) and an internet gateway (AWS::EC2::InternetGateway).

3. Once the template is uploaded to S3, click Next, then provide a stack name and parameters if needed. Complete the remaining stack deployment configuration steps, then initiate the stack creation operation.

4. On the stack events page, click the Deployment timeline tab next to Events.

You should now see the deployment timeline view rendering in real-time as CloudFormation provisions the VPC networking resources first, followed by the security group, subnet, and lastly, the EC2 instance.

CloudFormation in-progress stack deployment timeline viewFigure 4: Real-time CloudFormation in-progress deployment timeline view 

5. The timeline refreshes every five seconds to update the deployment progress. Five seconds later you have the below timeline view.

Updated CloudFormation deployment timeline after five second

Figure 5: Updated CloudFormation deployment timeline after five second

CloudFormation completed deployment timeline view Figure 6: CloudFormation completed deployment timeline view 

The above timeline shows, from the bottom to the top, bars representing each resource CloudFormation provisioned, with virtual vertical dependency lines showing the orders in which each resource operation occurred. The bars change colors as operations progress from blue (in-progress), to yellow consistency check, green (success) or red (failed).

CloudFormation completed deployment timeline view Figure 7: CloudFormation deployment timeline view – resource detail popover

Hover over any bar to see details like the start/end time of each deployment phase and the full resource name. The detailed information in the graph’s popover shows that CloudFormation created the InternetGateway resource in two seconds, then waited for 15-seconds to check if the resource was fully operational before marking as complete. This phase is called the resource consistency check phase, also known as the resource stabilization phase. It allows CloudFormation and other Infrastructure as Code (IaC) tools to ensure resilient deployments. To learn more, read this post about CloudFormation optimistic stabilization strategy.

Stack in a rollback complete state

When a stack deployment fails, CloudFormation rolls your stack back to its initial stable state before the current stack operation. The deployment timeline view below shows a failed stack operation in a complete rollback state. You can see the likely root cause resource highlighted in a red-and-white striped color so you can instantly identify it and start troubleshooting.

Deployment timeline view of a stack in rollback complete view 1

Deployment timeline view of a stack in rollback complete popover view 2

Figure 8: Deployment timeline view of a stack in rollback complete

Conclusion

The new CloudFormation deployment timeline view provides visibility into the orchestration flow and dependencies involved when CloudFormation provisions resources defined in your infrastructure-as-code templates. With this visual timeline view, you can quickly identify the root cause of deployment failures before operations complete and better understand the provisioning process. This feature is available now in all AWS regions where CloudFormation is supported. Visit the CloudFormation console to start using deployment timeline view.

About the authors:

Idriss Laouali Abdou

Idriss is a Senior Product Manager AWS, working on delivering the best experience for AWS IaC customers. Outside of work, you can either find him creating educational content helping thousands of students, cooking, or dancing.

Jamie To

Jamie is a Front End Engineer and has been delivering console features to AWS IaC customers for the last 3 years. Outside of work, Jamie enjoys drawing and playing foosball.

Puran Zhang

Puran has been contributing to IaC console as Front-end engineer for the last 4 years. Outside of work, you will likely find him in the kitchen, over the coffee bar, or on his hasty way to the next restaurant.

Дугин, Паскал и ние

Post Syndicated from Григор original http://www.gatchev.info/blog/?p=2655

Често чета канала в Телеграм на Александър Дугин. Интересен е.

Помните ли соц-вица как милиционерът се скрива в кофа за боклук, за да не го видят хората, но оставя фуражката си върху нея, за да ги „респектира“? Руското правителство е така. Официалните му изявления задължително са лъжа, част от „принципа на маскировка“ е. Но в същото време си има говорители на ниско ниво, да предупреждават хората за истинските му намерения, че да не смеят да им противоречат.

Дугин е може би най-известният от тези говорители. Той е… не точно консерватор, не точно и екстремен консерватор. Пред него екстремните консерватори са екстремни либерали – прочетете книгите му, ще се убедите. (И поопулите.) Властта в Русия е зад маската реално феодално-робовладелска, така че той е адекватният ѝ говорител. Например официалните реакции на Кремъл за победата на Тръмп бяха хладни, но Дугин обяви в канала си: „Победихме!“.

Този път ме впечатли друго негово изявление. Как следва безмилостно да се борим с трансджендърите и квадроберите, като символи на духовното падение и прочее.

То хубаво, ама трансджендърът е медицински проблем. Като примерно апандисита. Адекватната реакция към болен с апандисит е да го пратите да се оперира. Човек, който вместо това се бори с тия болни… какво е мнението ви за интелекта и адекватността му? Е, същото е за борбата с трансджендърите.

Квадроберите вероятно дори не знаете какво са. Деца (задължително западни), които според руската пропаганда са научени, че са животни, и изискват в училище да ходят на четири крака и да ползват по нужда сандъчета с пясък. Вест от оная вселена, в която американските войници се напиват с кока-кола и се търкалят пияни по земята. Какво е мнението ви за интелекта и адекватността на човек, който вярва в съществуването им? И в подкрепата на западните правителства и либералфашизма за тях? И би положил усилия, за да се бори с тях?

Естествено, Дугин няма как да вярва в това. Чак такъв идиот / луд ще е труден за контролиране, няма как да е неофициален говорител на руската стратегия. Но, като част от руската пропаганда, той търси сред нас идиотите / лудите, които биха му повярвали. Те са нужни на Русия.

Защо? Паскал казва: „Който може да ви накара да вярвате в абсурди, може да ви накара и да извършвате жестокости“. Да предаваш родината си, да предаваш или избиваш приятелите си – всичко, за което тези хора са нужни на Русия – е жестокост. Затова един от начините за намирането им е търсене кой би повярвал на абсурди. После тези хора биват прикотквани, вземани под контрол, организирани и запращани да съсипват „врага“ на Русия – България и нас лично.

Хубавото е, че тези хора лесно се издават, че вярват в такива неща. За разумния човек това е знак, че те са опасни идиоти / луди, от които трябва да се пази. Много внимателно – не знаете кога някой Дугин ще им прошушне, че вие сте рептил или либералфашист, и майчица България трябва спешно да бъде спасена от вас, дори на цената те да идат в затвора за убийство…

Предупредени сте.

Friday Squid Blogging: Squid-A-Rama in Des Moines

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/friday-squid-blogging-squid-a-rama-in-des-moines.html

Squid-A-Rama will be in Des Moines at the end of the month.

Visitors will be able to dissect squid, explore fascinating facts about the species, and witness a live squid release conducted by local divers.

How are they doing a live squid release? Simple: this is Des Moines, Washington; not Des Moines, Iowa.

Blog moderation policy.

AI Industry is Trying to Subvert the Definition of “Open Source AI”

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/ai-industry-is-trying-to-subvert-the-definition-of-open-source-ai.html

The Open Source Initiative has published (news article here) its definition of “open source AI,” and it’s terrible. It allows for secret training data and mechanisms. It allows for development to be done in secret. Since for a neural network, the training data is the source code—it’s how the model gets programmed—the definition makes no sense.

And it’s confusing; most “open source” AI models—like LLAMA—are open source in name only. But the OSI seems to have been co-opted by industry players that want both corporate secrecy and the “open source” label. (Here’s one rebuttal to the definition.)

This is worth fighting for. We need a public AI option, and open source—real open source—is a necessary component of that.

But while open source should mean open source, there are some partially open models that need some sort of definition. There is a big research field of privacy-preserving, federated methods of ML model training and I think that is a good thing. And OSI has a point here:

Why do you allow the exclusion of some training data?

Because we want Open Source AI to exist also in fields where data cannot be legally shared, for example medical AI. Laws that permit training on data often limit the resharing of that same data to protect copyright or other interests. Privacy rules also give a person the rightful ability to control their most sensitive information ­ like decisions about their health. Similarly, much of the world’s Indigenous knowledge is protected through mechanisms that are not compatible with later-developed frameworks for rights exclusivity and sharing.

How about we call this “open weights” and not open source?

Prompt Injection Defenses Against LLM Cyberattacks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/prompt-injection-defenses-against-llm-cyberattacks.html

Interesting research: “Hacking Back the AI-Hacker: Prompt Injection as a Defense Against LLM-driven Cyberattacks“:

Large language models (LLMs) are increasingly being harnessed to automate cyberattacks, making sophisticated exploits more accessible and scalable. In response, we propose a new defense strategy tailored to counter LLM-driven cyberattacks. We introduce Mantis, a defensive framework that exploits LLMs’ susceptibility to adversarial inputs to undermine malicious operations. Upon detecting an automated cyberattack, Mantis plants carefully crafted inputs into system responses, leading the attacker’s LLM to disrupt their own operations (passive defense) or even compromise the attacker’s machine (active defense). By deploying purposefully vulnerable decoy services to attract the attacker and using dynamic prompt injections for the attacker’s LLM, Mantis can autonomously hack back the attacker. In our experiments, Mantis consistently achieved over 95% effectiveness against automated LLM-driven attacks. To foster further research and collaboration, Mantis is available as an open-source tool: this https URL.

This isn’t the solution, of course. But this sort of thing could be part of a solution.

Subverting LLM Coders

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/subverting-llm-coders.html

Really interesting research: “An LLM-Assisted Easy-to-Trigger Backdoor Attack on Code Completion Models: Injecting Disguised Vulnerabilities against Strong Detection“:

Abstract: Large Language Models (LLMs) have transformed code completion tasks, providing context-based suggestions to boost developer productivity in software engineering. As users often fine-tune these models for specific applications, poisoning and backdoor attacks can covertly alter the model outputs. To address this critical security challenge, we introduce CODEBREAKER, a pioneering LLM-assisted backdoor attack framework on code completion models. Unlike recent attacks that embed malicious payloads in detectable or irrelevant sections of the code (e.g., comments), CODEBREAKER leverages LLMs (e.g., GPT-4) for sophisticated payload transformation (without affecting functionalities), ensuring that both the poisoned data for fine-tuning and generated code can evade strong vulnerability detection. CODEBREAKER stands out with its comprehensive coverage of vulnerabilities, making it the first to provide such an extensive set for evaluation. Our extensive experimental evaluations and user studies underline the strong attack performance of CODEBREAKER across various settings, validating its superiority over existing approaches. By integrating malicious payloads directly into the source code with minimal transformation, CODEBREAKER challenges current security measures, underscoring the critical need for more robust defenses for code completion.

Clever attack, and yet another illustration of why trusted AI is essential.

IoT Devices in Password-Spraying Botnet

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/iot-devices-in-password-spraying-botnet.html

Microsoft is warning Azure cloud users that a Chinese controlled botnet is engaging in “highly evasive” password spraying. Not sure about the “highly evasive” part; the techniques seem basically what you get in a distributed password-guessing attack:

“Any threat actor using the CovertNetwork-1658 infrastructure could conduct password spraying campaigns at a larger scale and greatly increase the likelihood of successful credential compromise and initial access to multiple organizations in a short amount of time,” Microsoft officials wrote. “This scale, combined with quick operational turnover of compromised credentials between CovertNetwork-1658 and Chinese threat actors, allows for the potential of account compromises across multiple sectors and geographic regions.”

Some of the characteristics that make detection difficult are:

  • The use of compromised SOHO IP addresses
  • The use of a rotating set of IP addresses at any given time. The threat actors had thousands of available IP addresses at their disposal. The average uptime for a CovertNetwork-1658 node is approximately 90 days.
  • The low-volume password spray process; for example, monitoring for multiple failed sign-in attempts from one IP address or to one account will not detect this activity.

AIs Discovering Vulnerabilities

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/ais-discovering-vulnerabilities.html

I’ve been writing about the possibility of AIs automatically discovering code vulnerabilities since at least 2018. This is an ongoing area of research: AIs doing source code scanning, AIs finding zero-days in the wild, and everything in between. The AIs aren’t very good at it yet, but they’re getting better.

Here’s some anecdotal data from this summer:

Since July 2024, ZeroPath is taking a novel approach combining deep program analysis with adversarial AI agents for validation. Our methodology has uncovered numerous critical vulnerabilities in production systems, including several that traditional Static Application Security Testing (SAST) tools were ill-equipped to find. This post provides a technical deep-dive into our research methodology and a living summary of the bugs found in popular open-source tools.

Expect lots of developments in this area over the next few years.

This is what I said in a recent interview:

Let’s stick with software. Imagine that we have an AI that finds software vulnerabilities. Yes, the attackers can use those AIs to break into systems. But the defenders can use the same AIs to find software vulnerabilities and then patch them. This capability, once it exists, will probably be built into the standard suite of software development tools. We can imagine a future where all the easily findable vulnerabilities (not all the vulnerabilities; there are lots of theoretical results about that) are removed in software before shipping.

When that day comes, all legacy code would be vulnerable. But all new code would be secure. And, eventually, those software vulnerabilities will be a thing of the past. In my head, some future programmer shakes their head and says, “Remember the early decades of this century when software was full of vulnerabilities? That’s before the AIs found them all. Wow, that was a crazy time.” We’re not there yet. We’re not even remotely there yet. But it’s a reasonable extrapolation.

EDITED TO ADD: And Google’s LLM just discovered an exploitable zero-day.

How Amazon Q reduced the time Amazon developers spent waiting for technical answers by 450k hours this year

Post Syndicated from Hank Cycyota original https://aws.amazon.com/blogs/devops/reducing-time-spent-waiting-with-amazon-q/

Introduction

Software development is complex and time consuming. Developers frequently need to stop building to get answers to hard, technical questions. What is the error in my code? How do I debug the logic? Where do I go to find this information? In 2024 Stack Overflow Developer Survey 53% of respondents agreed that waiting on answers disrupts their workflow, even if they know where to go find those answers. Similarly, 30% of respondents said knowledge silos impact their productivity ten times or more per week.

Our team – Amazon Software Builder Experience (ASBX) – leaned in to help solve this problem on behalf of Amazon developers. The ASBX organization has a mission to improve the software builder experience across tens of thousands of software engineers that work in all Amazon businesses. This includes the discovery tools that developers use to build and innovate on behalf of our customers. At Amazon, we have a wealth of software development expertise and an extensive knowledge base, but individual developers often have a hard time finding the exact information they need for the task at hand. They’re looking for a needle in a haystack. We have a few internal tools where Amazon developers go to connect with those subject matter experts (SME) but for the most complex questions, they might need to wait hours before they get a response. However, often the information they need is buried somewhere deep in our knowledge base. We saw an opportunity to pair new techniques in generative AI like retrieval augmented generation (RAG) with our extensive knowledge base to reduce the demand on those SMEs in the tools that our developers use every day. In this way, we would reduce the time our developers had to spend waiting for answers, allowing them stay in their workflow and continue delighting customers.

While we thought RAG would enable us to better assist our developers, we knew that our solution would need to pass rigorous security and privacy bars and scale to support the volume of documentation and questions that Amazon developers generate. Amazon Q Business met those requirements as well as removed some of the duplicative work that comes with managing a separate index and large language model. Additionally, Amazon Q Business comes with some out-of-the-box APIs that would allow us to integrate it with the tools that Amazon developers use as part of their discovery workflows. Finally, those APIs come with important hooks that would let us use the context within those tools to improve information retrieval and answer relevancy.

This year, Amazon Q Business has helped tens of thousands of Amazon developers answer questions and get back to building. With Amazon Q Business connected to our internal knowledge repositories, our developers are getting unblocked quicker to deliver results for customers; we’ve been able to reduce the time it takes for Amazon developers to find answers to technical questions from hours to just a few seconds. This year, Amazon Q Business has resolved over 1 million internal Amazon developer questions, reducing time spent churning on manual technical investigations by more than 450k hours.

Closing the discovery loop

Over its 30-year history, Amazon developers have generated a vast corpus of content to help them delight their customers. This includes community-generated content such as runbooks, dashboards, service-level documentation, structured Q&A, and program information. While we have an abundance of knowledge, finding the right answer to some of our more complex technical questions has been a challenge and the act of finding information pulls developers out of their workflow. When a developer is struggling to find an answer for a specific question, there are a few popular internal resources to get support from technical experts.

  • Developers can post a question on our internal Q&A boards (a tool called Sage) and wait for a reply. These questions are often complex in nature and require specific expertise to answer. The challenge is, answers aren’t immediate and the more obscure the question, the longer it can take for an SME to review and respond.
  • Developers can find the appropriate interest channel in Slack and ask there (often channels that are set up by a team of experts to provide support for a given problem domain). These questions are similarly complex and a developer benefits from asynchronous back and forth with the SME. This route can be faster than our Q&A boards, but it can still take hours to get a reply.

In both cases, the developer needs to wait for an answer from those SMEs to unblock their task. They could transition to the next task on their sprint board but now they need to context switch to something new (and often quickly switch back once the SME finally responds). What’s more, the answers to these questions often already exist somewhere in our knowledge base but the developer couldn’t find that needle in the collective haystack of tools and repositories that we have at Amazon.

We saw an opportunity to better connect Amazon developers with answers to their questions by integrating Amazon Q Business with those tools they were already using. We wanted this solution to take on the role of a subject matter expert in tools like Sage and Slack to provide a fast answer to questions to get the developer unstuck. We ingested our internal knowledge repository consisting of millions of documents into Amazon Q Business so our developers could get answers based on data across those repositories. Then, we integrated our Amazon Q Business instance with the tools where our developers commonly ask questions. Finally, we used context inherent to the tools themselves (e.g., the Slack channel in which a user was asking a question or the specific Sage subject they were posting to) to provide more useful responses. This approach has resulted in three primary benefits:

  • Swift adoption: We integrated the Q&A capabilities of Amazon Q Business into tools like Slack and Sage to make it part of the workflows our developers use every day. It also prevented us from having to create (yet) another tool that our developers needed to visit to get answers to questions. As a result, Amazon Q Business has already answered over 1 million internal Amazon developer questions this year.
  • More precise answers: This approach has enabled better responses to developer questions via Amazon Q Business by using the context that is readily available on the tool. In this way, we can narrow the retrieval scope from potentially millions of documents. Developers report that answers are more helpful when we scope retrieval in this manner (versus when no scope is present).
  • Faster answers: Leveraging Amazon Q Business has reduced the time it takes for a developer to get an answer to seconds, getting them unblocked so they can delight customers.

The remainder of this article touches briefly on how we set up our Amazon Q Business instance and how we integrated it with downstream tools. We then go into more depth around how we leveraged tool-specific context to provide better answers in service of getting our developers unstuck faster.

Setting up Amazon Q Business: Integrating Q Business with our knowledge repositories

We took a straightforward approach to setting up our Amazon Q Business application and followed the steps outlined in the service documentation here. We staged our knowledge repositories in S3 and used the Amazon Q Business S3 Connector to ingest those documents into our index (more info on how to use those S3 connectors here). We have a lot of content that isn’t useful in retrieval – pre-processing of our documents in S3 to remove stale content allows us to reduce our repository of over ten million potentially useful documents to under four million relevant ones. We also stage in S3 to enrich content with metadata (e.g., document type, team or service name, URL hierarchy) that isn’t in the source repository in order to take advantage of more Q features (e.g., filtering, boosting).

Integrating Amazon Q Business: Putting Q Business where users are

We leveraged a single Amazon Q Business application that hosts all our curated content to quickly release our desired experience in places where our developers ask questions. Also, leveraging one Amazon Q Business application lets us provide a consistent experience on the tools we integrate with, ensuring users are getting the same answers from the same dataset.

As we considered the UX for these integrations, our goal was that these experiences complement the existing workflow in the tools developers use. For instance, rather than increasing the cognitive load on the developer by adding a chat experience in the corner of Sage, we chose to automatically respond with answers to questions on the Q&A board. Similarly, developers can invoke Amazon Q Business on Slack in an interest channel to get answers to questions. We learned early that users have expectations around what sort of questions a bot is able to answer based on where they are interacting with it. For instance, customers were frustrated at a prototype experience on Sage that didn’t actually include the Q&A data native to that tool. Our prerequisite for onboarding new tools is to make sure we have the data for that tool and have considered other expectations users might have.

Enhancing our solution: Improving retrieval through surface-level context

By integrating Amazon Q Business directly with applications that developers use every day we’ve been able to leverage that information as context to improve retrieval accuracy and give better responses to developers. A common technical question our Amazon Q Business application answers is “How do I onboard to XX service?” Depending on the service in question (e.g., How common is the service name? Have many other actors onboarded to it?), Amazon Q Business might retrieve context outside of the authoritative set of documentation we want it to use. This can be confusing to the reader and reduce trust in the answers. However, if we know that a developer is asking that question in the XX-service@ Slack channel, we can narrow the retrieval scope to just the content related to XX-service.

As an example of where this helps, there is an internal Amazon service framework called Coral. Take a common question like “How do I maintain my Coral dashboard?” The answer to this question can vary by team, most of which maintain specific documentation about their dashboards. Asking this question without scoping will list a lot of good best practices around dashboards. However, if we know that the question is being asked in a specific team channel on Slack, it can use that context to scope to that specific team’s documentation to provide a more precise answer.

We scope documents with the Amazon Q Business filter attribute, which allows us to customize and control chat responses based on the document metadata reflected in index fields. We can break this down to the following steps:

  • We capture and associate document-specific metadata during ingestion.
  • We enable SMEs to define a topic space based on that metadata. A topic space is a collection of authoritative documents (spread across multiple repositories) specific to their knowledge domain. To use an example for an external-facing repository, a topic space could encompass all the Dynamo content on AWS Docs as specified by a root URL (like https://docs.aws.amazon.com/dynamodb). In this case, we would include all the URLs under that root in that topic space.
  • With the topic space defined, we leverage the Amazon Q Business metadata filters to restrict its RAG down at runtime to just the content in the topic space. Then, when a user asks a question about that topic space, say in a Slack interest channel on DynamoDB, the filters are applied and a domain-specific answer is generated from the SME-specified, authoritative content. Our call looks like this and the service documentation to set up your own is here.

  • In cases where the topic space does not contain an answer to the developer’s question (maybe the documentation hasn’t been updated or the question is too specific), we also added an opt-in user configuration to enable falling back to general knowledge. This ignores the filters and retries the original query to take advantage of the whole dataset.

Conclusion

This post described our process to integrating Amazon Q Business into tools where internal Amazon developers are looking for support. It also describes how we used context from these tools to improve the responses we provide to customers by using the inbuilt Amazon Q Business filter attributes.

You can also leverage this approach to make it easier for your developers to find answers to questions. For more information on how to do this, along with other ways you can make Amazon Q work for you, visit Getting started with Amazon Q Business.

Alexandru Baluta

Alexandru Baluta is a Senior Software Development Engineer at Amazon Web Services leading teams that specialize in Generative AI and Knowledge Discovery. His work enables enterprise decision-making, information flow, and knowledge sharing within Amazon’s engineering community and beyond. In his free time, he enjoys exploring new places and discovering unique restaurants.

Hank Cycyota

Hank Cycyota is Product Manager at Amazon Web Services and leads the teams that help Amazonians find the information they need so they can delight customers. He loves helping his teams work backwards from ambiguous problem statements to data-driven solutions. Outside of work, Hank spends time running and trying new recipes from his library of cookbooks.

Roger Grimes on Prioritizing Cybersecurity Advice

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/roger-grimes-on-prioritizing-cybersecurity-advice.html

This is a good point:

Part of the problem is that we are constantly handed lists…list of required controls…list of things we are being asked to fix or improve…lists of new projects…lists of threats, and so on, that are not ranked for risks. For example, we are often given a cybersecurity guideline (e.g., PCI-DSS, HIPAA, SOX, NIST, etc.) with hundreds of recommendations. They are all great recommendations, which if followed, will reduce risk in your environment.

What they do not tell you is which of the recommended things will have the most impact on best reducing risk in your environment. They do not tell you that one, two or three of these things…among the hundreds that have been given to you, will reduce more risk than all the others.

[…]

The solution?

Here is one big one: Do not use or rely on un-risk-ranked lists. Require any list of controls, threats, defenses, solutions to be risk-ranked according to how much actual risk they will reduce in the current environment if implemented.

[…]

This specific CISA document has at least 21 main recommendations, many of which lead to two or more other more specific recommendations. Overall, it has several dozen recommendations, each of which individually will likely take weeks to months to fulfill in any environment if not already accomplished. Any person following this document is…rightly…going to be expected to evaluate and implement all those recommendations. And doing so will absolutely reduce risk.

The catch is: There are two recommendations that WILL DO MORE THAN ALL THE REST ADDED TOGETHER TO REDUCE CYBERSECURITY RISK most efficiently: patching and using multifactor authentication (MFA). Patching is listed third. MFA is listed eighth. And there is nothing to indicate their ability to significantly reduce cybersecurity risk as compared to the other recommendations. Two of these things are not like the other, but how is anyone reading the document supposed to know that patching and using MFA really matter more than all the rest?

Tracking World Leaders Using Strava

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/tracking-world-leaders-using-strava.html

Way back in 2018, people noticed that you could find secret military bases using data published by the Strava fitness app. Soldiers and other military personal were using them to track their runs, and you could look at the public data and find places where there should be no people running.

Six years later, the problem remains. Le Monde has reported that the same Strava data can be used to track the movements of world leaders. They don’t wear the tracking device, but many of their bodyguards do.

Simson Garfinkel on Spooky Cryptographic Action at a Distance

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/simson-garfinkel-on-spooky-cryptographic-action-at-a-distance.html

Excellent read. One example:

Consider the case of basic public key cryptography, in which a person’s public and private key are created together in a single operation. These two keys are entangled, not with quantum physics, but with math.

When I create a virtual machine server in the Amazon cloud, I am prompted for an RSA public key that will be used to control access to the machine. Typically, I create the public and private keypair on my laptop and upload the public key to Amazon, which bakes my public key into the server’s administrator account. My laptop and that remove server are thus entangled, in that the only way to log into the server is using the key on my laptop. And because that administrator account can do anything to that server­—read the sensitivity data, hack the web server to install malware on people who visit its web pages, or anything else I might care to do­—the private key on my laptop represents a security risk for that server.

Here’s why it’s impossible to evaluate a server and know if it is secure: as long that private key exists on my laptop, that server has a vulnerability. But if I delete that private key, the vulnerability goes away. By deleting the data, I have removed a security risk from the server and its security has increased. This is true entanglement! And it is spooky: not a single bit has changed on the server, yet it is more secure.

Read it all.

Using Semantic Versioning to Simplify Release Management

Post Syndicated from Brandon Kindred original https://aws.amazon.com/blogs/devops/using-semantic-versioning-to-simplify-release-management/

Any organization that manages software libraries and applications needs a standardized way to catalog, reference, import, fix bugs and update the versions of those libraries and applications. Semantic Versioning enables developers, testers, and project managers to have a more standardized process for committing code and managing different versions. It’s benefits also extend beyond development teams to end users by using change logs and transparent feature documentation. This alleviates the operational burden of communicating changes for each release cycle.

In this post, we dive deep into how Semantic Versioning works and how to use the NodeJS package semantic-release/npm in a GitHub Actions continuous integration and continuous delivery (CI/CD) pipeline to automatically version an Amazon Web Services (AWS) Cloud Development Kit (AWS CDK) project. Once we’re done, you’ll be ready to deliver AWS CDK projects that are automatically versioned so your team can focus more on code instead of versioning for each release.

How does Semantic Versioning work?

With Semantic Versioning, version number changes convey a specific meaning about the underlying code change. This helps others to understand what has changed from one version to the next.

Semantic Versioning is defined in a Major.Minor.Patch format, which is a guideline to track the scope and potential impact of changes for feature development, major updates and bug fixes. The Major version number change signifies that this release will have breaking changes and any upgrade to this version should be validated for backward compatibility. The Minor version number change signifies a feature release in a backward-compatible manner. Finally, the Patch version number signifies a small insignificant change or a bug fix and users can upgrade to this version without introducing breaking changes or new features.

Each version number is always incremented by one digit and when a higher digit increments, the lower digits reset to zero. For example, version 1.5.2 means that the software is in its first major version, and has released 5 features with 2 patches implemented. When a new feature is added, it will be released as version 1.6.0. If there are any bugs reported and a fix is release for that bug, the next release version will be 1.6.1. For a version 2.0.0 release there will be breaking changes, and may not be backward compatible with previous 1.x.x versions.

What is semantic-release?

Now that we have covered how Semantic Versioning works, and why it’s useful in software projects, let’s review semantic-release. It is a Node.js tool that simplifies Semantic Versioning management. Semantic-release can do more than just apply Semantic Versioning to your projects. With a variety of plugins available, you can track what sort of changes are being made with commit analysis or by generating a changelog for each release. This automates what would otherwise have been a manual and time-consuming process to create and review roadmaps and documentation tracking the new features and fixes that comprise a release. Semantic-release is also straightforward to integrate with CI tools such as GitHub Actions, GitLab CI, Travis CI, and CircleCI 2.0 workflows.

Unfortunately, if your commit messages don’t match the format semantic-release requires, the automatic versioning won’t work correctly. To verify that commit messages are in the right format, you can integrate tools such as commitizen or commitlint, which can validate that commit messages are in a valid format.

Using semantic-release

Commit message formats

By default, semantic-release uses Angular Commit Message Conventions, however the commit message format can be altered by using config options. Let’s take a quick look at the three different types of commit messages, fixes, features, and breaking changes.

Patches and fixes

For patch or fix commits, you need to start your commit message with “fix(context):”. This tells semantic-release that this is a minor patch—meaning that if your version is 0.0.1, after this commit is merged the version will be incremented to 0.0.2. Following is an example commit message.

fix(printer): inform user when printer is out of paper

Features

Feature commit messages start with “feat(context):” which indicates to semantic-release that this is a feature release, also referred to as a minor release. If your version is 0.1.0, after a feature commit is merged, the version will be incremented to 0.2.0. Following is an example of a feature commit.

feat(printer): add option for printing in color

Breaking changes

Breaking change commits are intended for marking a major breaking change—meaning that the commit introduces changes that are not compatible with existing or previous versions. The way that commit messages are marked as breaking changes is slightly different than the previous commit types. For a breaking change, the commit footer needs to include “BREAKING CHANGE:”. For example, a breaking change commit, might look like the following.

perf(printer): remove color printing option

BREAKING CHANGE: The color printing option has been removed. The default black and white printing option is always used for performance reasons.

Release change log

To generate a release change log, we only need to add the semantic-release/changelog plugin to the package.json file. We’ll demonstrate how to do this in the next section.

Adding Semantic Release to an AWS CDK project

To demonstrate semantic-release in action we will build an example with AWS CDK and the NPM semantic-release library. All code provided in the remainder of this blog can be found in the semantic-versioning demo repository (aws-cdk-semantic-release) on GitHub.

To get started we’ll need to create a Node.js CDK application, add semantic-release and its plugins, commit changes, then build the project. If you don’t have AWS CDK installed yet, check out the Getting Stated with CDK guide.

To begin, navigate to the folder where the project will be saved. Next, we initialize a new AWS CDK project and add semantic-release. Then, we configure the branches that Semantic Versioning should be applied to and add a few NPM plugins to extend the functionality of semantic-release. While there are many plugins available, only a few are needed to get started. Below, we’ll walk through which plugins to install and how to install them.

Initiate a new AWS CDK Typescript project and add semantic-release

In a command terminal, navigate to the folder where you want to store your AWS CDK project and run the following three commands. The first line will create the project and the next two will install the semantic-release NPM and Git plugins in the AWS CDK project.

cd <<PROJECT_FOLDER>>
cdk init app --language typescript
npm install @semantic-release/npm -D
npm install @semantic-release/git -D

Define which branches to apply versioning to

We need to tell NPM which branches can trigger a new release. In the example we’ll use the main branch and the staging branches for release. We will add a new section to the package.json file along with the branches we want to use for releases.

"release": {
  "branches": ["main"]
}

Add supporting plugins to package.json

In order for semantic-release to pick up commits, generate release notes, and be able to perform a release with GitHub we need to add the commit-analyzer, release-notes-generator, changelog, NPM, Git, and GitHub plugins. Add the following plugins section to the package.json file after the “release” section we added in the previous step.

"plugins": [
    "@semantic-release/commit-analyzer",
    "@semantic-release/release-notes-generator",
    "@semantic-release/changelog",
    "@semantic-release/npm",
    [
        "@semantic-release/git",
        {
            "assets": [
                "package.json",
                "CHANGELOG.md"
            ],
            "message": "chore(release): ${nextRelease.version}[skip ci]\n\n${nextRelease.notes}"
        }
    ],
    "@semantic-release/github"
],

Putting it all together, our package.json file should look similar to the following.

{
    "name": "aws-cdk-semantic-release",
    "version": "0.1.0",
    "bin": {
        "aws-cdk-semantic-release": "bin/aws-cdk-semantic-release.js"
    },
    "scripts": {
        "build": "tsc",
        "watch": "tsc -w",
        "test": "jest",
        "cdk": "cdk"
    },
    "plugins": [
        "@semantic-release/commit-analyzer",
        "@semantic-release/release-notes-generator",
        "@semantic-release/changelog",
        "@semantic-release/npm",
        [
            "@semantic-release/git",
            {
                "assets": [
                    "package.json",
                    "CHANGELOG.md"
                ],
                "message": "chore(release): ${nextRelease.version} [skip ci]\n\n${nextRelease.notes}"
            }
        ],
        "@semantic-release/github"
    ],
    "release": {
        "branches": [
            "main"
        ]
    },
    "devDependencies": {
        "@semantic-release/changelog": "^6.0.3",
        "@semantic-release/git": "^10.0.1",
        "@semantic-release/npm": "^11.0.2",
        "@types/jest": "^29.5.12",
        "@types/node": "20.11.16",
        "aws-cdk": "2.127.0",
        "jest": "^29.7.0",
        "ts-jest": "^29.1.2",
        "ts-node": "^10.9.2",
        "typescript": "~5.3.3"
    },
    "dependencies": {
        "aws-cdk-lib": "2.127.0",
        "constructs": "^10.0.0",
        "source-map-support": "^0.5.21"
    }
}

With the necessary package.json changes in place, we can commit our code and build the project again.

git commit -m "feat(semver): added semantic release plugins and set main branch for versioning"
npm run build

Configure GitHub Actions

In the projects root folder, we are going to create folders for .github/workflows so that we can configure GitHub Actions release steps.

mkdir .github
cd .github
mkdir workflows
cd workflows

Create a file called release.yaml in the workflows folder that has the following.

name: Release
on:
  push:
    branches:
      - main
jobs:
  release:
    runs-on: ubuntu-latest
    steps:
      - name: Checkout Code
         uses: actions/checkout@v3
      - name: Setup Node.js
         uses: actions/setup-node@v3
         with:
           node-version: '20.8.1'
      - name: Install Dependencies
         run: npm install
      - name: Semantic Release
         env:
           GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
           NPM_TOKEN: ${{ secrets.NPM_TOKEN }}
         run: npx semantic-release

The GITHUB_TOKEN is automatically generated and managed by GitHub Actions, so we don’t need to worry about retrieving or defining this value in our GitHub Actions steps. However, NPM_TOKEN is not automatically provided to us, so we need to define the NPM token. To do this we need to login to npmjs.com and create an account. Once we’re logged in, we need to create an access token. Once the NPM access token is created, then we need to add the token to GitHub secrets.

Verify Semantic-Release is setup correctly

Now that we have everything configured, new merges and commits to the main branch will kick off a CI/CD pipeline through GitHub Actions that builds the project and increments the version. To verify that everything is working correctly, we’ll alter the CDK code to include an AWS Lambda function. Afterward, we’ll commit changes to the main branch to verify that semantic-release is working correctly.

Make a change, commit, push and verify

In the AWS CDK project lib/aws-cdk-semantic-release-stack.ts file we’ll update the visibilityTimeout duration to 600, then commit the changes. We want to be sure to use the Semantic Versioning format for the commit message so that our changes are versioned correctly. For this we use the following commit message.

“fix(sqs-visibility): increased visibility timeout to 600”

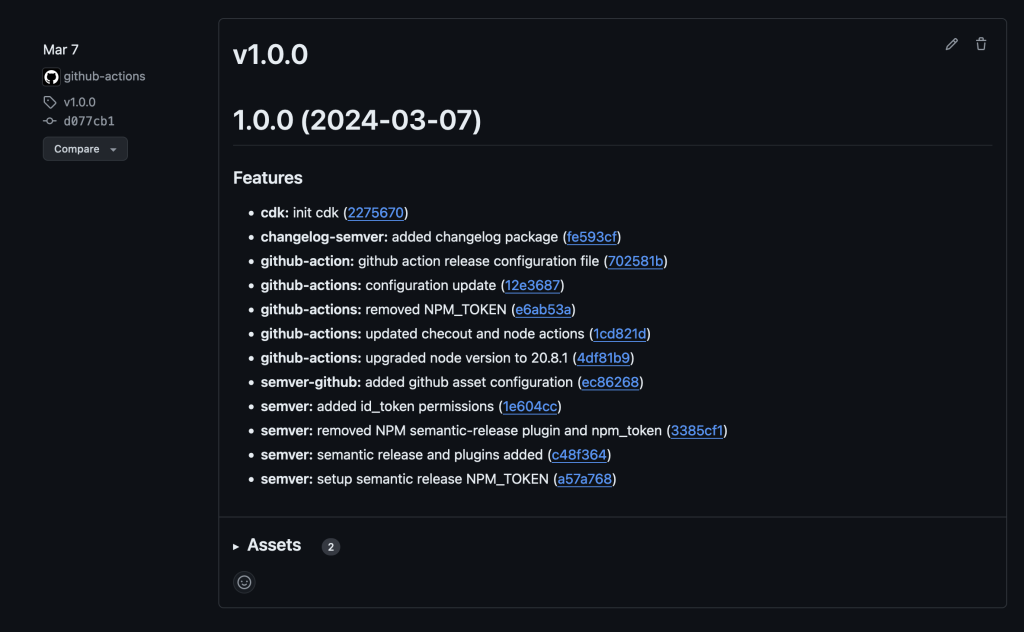
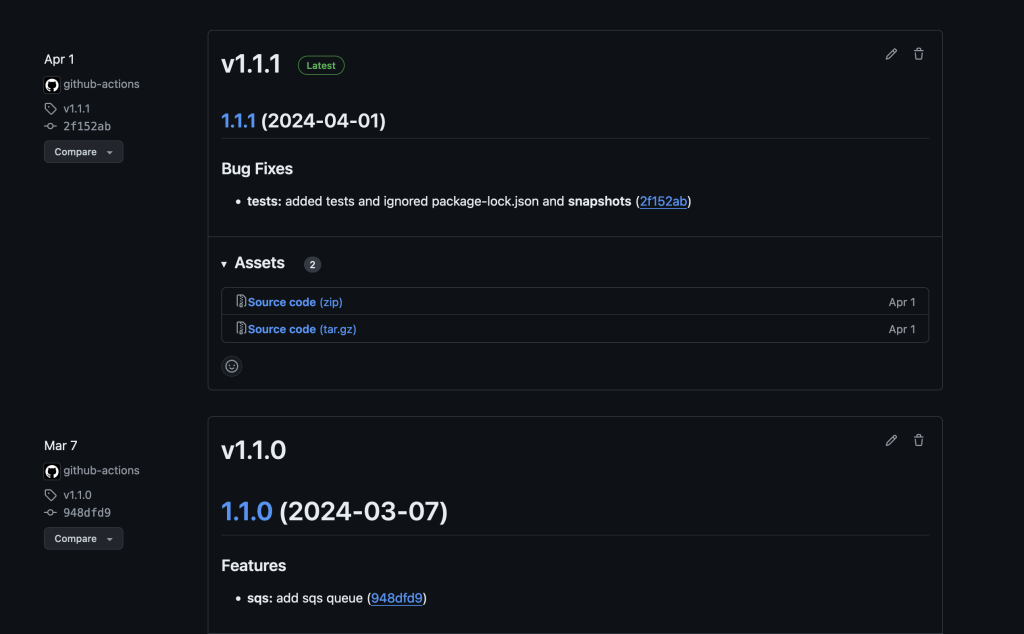
After committing the changes, we push the changes to the remote GitHub repository to initiate the GitHub Actions build process. Once the build is complete, we see that the build number has been incremented from the previous version. You can review the releases for the sample code to see how it has been versioned. Following are examples of what it should look like before and after executing this. Please note that the version numbers depicted may not match yours.

GitHub releases view with information about release v1.1.0 including features and assets that were updated as part of v1.1.0

Screenshot of GitHub releases page showing release 1.0.0 and the associated features changelog

Figure 1 – Before the new commits

GitHub releases view with information about release v1.1.1 followed by the previous release v1.1.0.

Screenshot of GitHub releases page showing a previous release and the latest release along with their respective versions of 1.1.0 and 1.1.1

Figure 2 – After GitHub Actions generates a new build

Conclusion

Semantic Versioning offers a structured and reliable way to manage software changes. When paired with the significant benefits of using Node.js packages like semantic-release, version management can become effortless. All of this enables automated version management Node.js projects such as AWS CDK pipelines for automated code deployment. It enhances clarity, stability, and collaboration, while also supporting automation and fostering user confidence.

By adopting Semantic Versioning, development teams can achieve more predictable and efficient workflows, ultimately leading to higher quality software. It also builds confidence among users without going into much details with respect to software upgrades and backward compatibility. As a best practice, start incorporating Semantic Versioning for existing and future applications.

Contact an AWS Representative to know how we can help accelerate your business.

Reference

CDK setup and deployment of application with CDK V2 Construct:

Headshot of Brandon Kindred (CAA), a white man with short hair, a beard and wearing a black shirt

Brandon Kindred

Brandon is a Cloud Application Architect at AWS ProServe where he helps companies achieve their cloud goals through tailored strategies and cost-effective solutions. With a passion for teaching, he enjoys empowering others to harness the full potential of cloud technologies while optimizing their cloud spend. Brandon also enjoys providing guidance on development best practices, ensure teams build resilient and scalable applications in the cloud.

Sunita Dubey (Sr CAA)

Sunita Dubey

Sunita Dubey is a senior Cloud Application Architect based out of New Jersey. She focuses on designing, architecting and delivering end to end solutions for customers in financial domain. She has solved multiple customer challenges to move their workload to AWS and saved cost in the migration process. She insists on highest standard in all the deliverables.

Leverage Amazon Q Developer and AWS Chatbot within Slack

Post Syndicated from Jonathan Wong original https://aws.amazon.com/blogs/devops/leverage-amazon-q-developer-and-aws-chatbot-within-slack/

The release of Amazon Q Developer and its ability to be integrated into AWS Chatbot allows users who use Microsoft Teams or Slack to stay within their communication platform and interact with a conversational generative artificial intelligence (AI) AWS expert.

Amazon Q Developer is a conversational generative AI chatbot that provides AWS assistance in the form of best practices, documentation, and answers your AWS related questions. AWS Chatbot is a service that lets you interact with AWS services directly from your communications platform such as Microsoft Teams, Amazon Chime, or Slack. Users can ask Q about best practices, building solutions, troubleshooting issues, and more, creating a productive and collaborative environment. Users can also interface with Chatbot to run AWS CLI commands or open support cases all within Slack.

In this post, we show you how you can leverage Q Developer and Chatbot in your Slack workspace by highlighting a number of use cases along with solution screenshots that can enhance a company’s AWS productivity. We will also showcase an architecture diagram, detailing the flow of actions and the use of different services. To learn more about how to implement Q Developer and Chatbot in Slack, refer to this documentation.

Disclaimer: The information and solutions provided by Q Developer are based on patterns from AWS-related data and best practices. While we strive to offer accurate and helpful guidance, please note that the suggestions may not always be fully accurate or applicable to every situation. It is essential to conduct additional research and verify the information with official AWS documentation or consult with AWS support before implementing any recommendations. Always use your judgment and consider the specific requirements of your environment when making decisions based on AI-generated advice.

Leveraging Q Developer and Chatbot

Q Developer and Chatbot serve a wide range of personas across an organization, catering to both AWS-savvy users and those with limited cloud expertise. Software engineers, for instance, can leverage Q Developer to quickly locate documentation, troubleshoot issues, or find best practices, streamlining their workflow. Security engineers can interact with Chatbot to monitor incidents and receive real-time alerts. Even non-technical users, like project managers or operations staff, can benefit from these tools without needing deep cloud knowledge. Together, these tools enhance productivity and collaboration across the company, regardless of technical expertise.

Use Cases

The use cases section is split into two categories, one for Q Developer, and the other for Chatbot. Both services provide unique abilities to interact with AWS to get the response you are looking for and can be accessed by sending a message to @aws on Slack. Q Developer allows users to ask questions in natural language and responds back with a response and a list of sources. Chatbot allows users to open support cases and to run a number of AWS CLI commands for services such as S3, Lambda, and CloudWatch.

Q Developer Use Cases

Q Developer is a versatile tool designed to assist teams for a number of AWS related use cases. In this post, we will focus on training and onboarding, troubleshooting issues, and implementing AWS best practices.

Training and Onboarding

Benefit: Q Developer can act as a virtual learning assistant, providing personalized training and learning paths for users based on their role, skill level, and current projects. It helps team members stay updated with the latest AWS features and best practices, enhances their skills, and ensures that they can leverage AWS services effectively and efficiently. By offering targeted resources, Q Developer supports continuous learning and helps users prepare for AWS certifications or new roles.

Use Case: AWS Beginner Recommendations. When a new employee joins the team, Q Developer can help them get up to speed by suggesting beginner-level tutorials and essential AWS concepts based on the team’s current tech stack and projects.

The conversation covers recommendations for resources to learn more about AWS, including AWS Documentation, AWS Training and Certification, AWS Blogs and Community, and AWS re:Invent and other events.

Figure 1 – AWS Beginner Recommendations

Use Case: Certification Guidance. An employee aims to get another AWS certification. They can ask Q Developer to provide a structured learning path with recommended courses, study guides, whitepapers, and practice exams to prepare effectively.

The conversation discusses a structured learning path to prepare for the AWS Machine Learning Specialty Certification, covering topics like the AWS Certified Cloud Practitioner certification, the AWS Certified Machine Learning - Specialty certification, and recommended study materials and practices.

Figure 2 – Certification Guidance

Troubleshooting Issues

Benefit: Q Developer provides targeted troubleshooting guidance, helping users to diagnose and resolve issues efficiently. By leveraging AWS service documentation, best practices, and community discussions, Q Developer reduces the time spent on searching for solutions and allows users to focus on resolving issues faster. This improves operational efficiency and minimizes downtime or disruptions.

Use Case: Optimization Recommendations. A developer is facing an issue with running their application on EC2 during peak hours and is looking for recommendations to diagnose the issue.

The conversation provides recommendations to address performance issues with an EC2 instance, including EBS volume configuration, network optimization, system optimization, and cost-effective solutions.

Figure 3 – Optimizations Recommendations

Use Case: Service Troubleshooting. An engineer is working on configuring API Gateway with their application but receives a 504 Gateway Timeout error. Q Developer can look up HTTP response codes for specific services and recommend a plan to tackle the issue.

The conversation discusses troubleshooting a 504 Gateway Timeout error with an API Gateway, providing steps to check CloudWatch logs, review the Lambda function, optimize the Lambda function's performance, and implement client-side retry logic.

Figure 4 – Service Troubleshooting

Best Practices

Benefit: Q Developer provides access to AWS best practices, ensuring that users can build, manage, and maintain their cloud infrastructure effectively. By adhering to best practices, users can optimize their applications for performance, security, scalability, and cost-efficiency. Q Developer helps users stay informed about evolving best practices for using AWS services, ensuring their deployments are up-to-date and compliant with industry standards.

Use Case: Designing Resilient Architectures. A solutions architect is designing a new application on AWS and wants to ensure it’s highly available and fault-tolerant. By asking Q Developer for best practices, they can receive guidance on a number topics including region selection, software, architecture, and deployment strategies to maximize uptime and reliability.

The conversation covers best practices for designing a highly available and fault-tolerant application on AWS, including region selection, alignment to demand, software and architecture, data management, hardware and services, process and culture, deployment strategies, and monitoring and logging.

Figure 5 – Designing Resilient Architectures

Use Case: Deploying Applications for Operational Excellence. An engineer is looking for best practices to deploy an application onto AWS Elastic Beanstalk. Q Developer can assist with providing specific tips for the job that conforms with AWS’ operational excellence pillar found in the AWS Well-Architected Framework.

Recommends several best practices such as choosing the right deployment policy, using rolling updates, implementing auto scaling, and optimizing for content delivery.

Figure 6 – Operational Excellence

Chatbot Use Cases

Chatbot can be used to run AWS CLI commands, open support cases, and more within Slack. To learn more about how to get started with these commands, please visit Chatbot’s documentation and refer to this AWS Blog for additional information.

Using Chatbot and Q Developer Together

We can use Chatbot and Q Developer together to provide clarity in situations where an organization receives alerts on their Slack channel. For example, you can configure Chatbot to receive notifications using Amazon Simple Notification Service based off of rules set up within Amazon EventBridge and it will be delivered directly into your Slack channel. Given that an organization can have many types of notifications enabled for their AWS services, there may be times where the message that is being sent to Slack can be confusing and not well understood. You can take the message provided to you from the notification and provide that as context to Q Developer to help you dive deep into the situation and help figure out next steps. To learn more about setting up notifications and having them be sent to your Slack, please refer to this documentation.

Notification from Chatbot on Slack indicating to the user that there is an issue.

Figure 7 – Chatbot Error Notification

Q to address the issue, such as verifying the instance's health, ensuring the Auto Scaling group's configuration is correct, and reviewing the instance's configuration.

Figure 8 – Q Developer Deep Dive into Chatbot Notification

Architecture Diagram

Diagram illustrating the flow of information between a user, Slack Workspace, AWS Chatbot, and an Amazon Q Developer.

Figure 9 – Solution Overview 

  1. A user logs into Slack and can either ask a question, run AWS command(s), or open a support case.
  2. Slack sends the request to Chatbot which then validates that it can be processed from the channel role and associated guardrail policies, both of which are setup through AWS Identity and Access Management. If the request follows the Chatbot use case(s), we can disregard step 3 and move to step 4.
  3. The request is forwarded to Q Developer where it is processed and formulates a response which is then sent back to Chatbot. Chatbot will then relay the response back to Slack which is displayed to the user.
  4. Logs are captured from the original message and the response and can be located within Amazon CloudWatch


Next Steps

Refer to these AWS documentation links that cover how to get started with setting up Q Developer and Chatbot in Slack. It is important to follow the order of the listed documents and to adhere to each of the steps listed to be able to get started with using the solution.

Integration Steps

  • Setting up AWS Chatbot
    1. AWS Chatbot Getting Started documentation outlines the steps to set up AWS Chatbot for interacting with AWS infrastructure. It covers steps such as setting up an AWS account, configuring IAM permissions, and setting up Amazon SNS topics for notifications.
  • Configuring Slack with Chatbot
    1. This documentation shows how to integrate AWS Chatbot with Slack, enabling AWS notifications and interactions in Slack channels. It covers Slack client and channel configuration and testing notifications from AWS services to Slack. Once completed with setting up Slack with Chatbot, refer back to the main Chatbot documentation where you can additional links on monitoring AWS services, customizing Chatbot and performing CLI commands on the lefthand side.
  • Setting up Q Developer with Chatbot
    1. After following the previous documentation steps,you can now integrate Amazon Q Developer with AWS Chatbot in Slack, allowing users to ask questions about AWS services directly in chat. It includes IAM role setup with managed policies and necessary configuration steps. Once completed, this will allow you to use Q Developer through Chatbot’s interface on Slack.

Conclusion

This post highlights how using Q Developer and Chatbot within Slack can boost productivity for a number of use cases. Individuals, teams, and organizations can use these two services’ capabilities to navigate the intricacies of AWS, troubleshoot ongoing issues, and provide real-time guidance all without leaving the familiarity of Slack.

Jonathan Wong

Jonathan Wong is a Solutions Architect at AWS assisting with initiatives within Strategic Accounts. He is passionate about solving customer challenges and has been exploring emerging technologies to accelerate innovation.