Tag Archives: Uncategorized

Introducing the next-level of AI-powered workflows with Amazon Q Developer inline chat

Post Syndicated from Jose Yapur original https://aws.amazon.com/blogs/devops/amazon-q-developer-inline-chat/

Earlier today, Amazon Q Developer announced support for inline chat. Inline chat combines the benefits of in-IDE chat with the ability to directly update code, allowing developers to describe issues or ideas directly in the code editor, and receive AI-generated responses that are seamlessly integrated into their codebase. In this post, I will introduce the new inline chat and discuss when to use this new capability to get the most value from Amazon Q Developer.

Background

I started using Q Developer (previously called Amazon CodeWhisperer) when it first launched in June 2022. This initial release included support for inline suggestions, which automatically generated code completions based on existing code and comments. Inline suggestions resulted in significant productivity gains.

Later that year, OpenAI released ChatGPT, and generative AI-powered chat became a hot topic. Personally, I found the chat experience more helpful when I was unsure how to accomplish a task. The chat interface not only generated code, but also provided explanatory context. I preferred to use inline suggestions when I knew what I was doing, and chat when I was learning something new. Therefore, I was thrilled when Amazon Q Developer added chat to the IDE in 2023, as I could use it to explain coding concepts, generate code and tests, and improve existing code. Having chat in the IDE helps me stay on task and in a state of focus and flow.

I have been using both inline suggestions and chat for the past year equally. While I love both options, I still felt there was room for improvement. For example, when fixing a bug, inline suggestions excel at generating new code, but do not easily allow me to update the existing code. Chat allows me to update existing code, but the response is provided in the chat window rather than being directly integrated into my code. This is where inline chat aims to improve the workflow.

Introducing inline chat

Today, we are excited to announce inline chat for Visual Studio Code (VS Code) and JetBrains. Inline chat allows me to provide additional context, such as a description of the bug I’m trying to fix, directly in the code editor. The AI-generated response is then seamlessly merged into my existing code, rather than requiring me to copy and paste from a separate chat window. I can easily review the suggested changes and accept, or decline, them with minimal effort. This new capability is ideal for editing an existing file to fix issues, optimize code, refactor code, add comments. And, it’s included in Amazon Q Developer’s expansive Free tier.

Inline chat is really powerful and helps me do more complex things quickly and accurately. There’s a lot that goes into building an assistant, but one important component is the underlying model, and inline chat is the first Amazon Q Developer capability powered by the latest version of Anthropic’s Claude 3.5 Sonnet, which launched on October 22nd. This new model “shows wide-ranging improvements on industry benchmarks, with particularly strong gains in agentic coding.” As I write this, upgraded Claude 3.5 Sonnet is the top performing model on the SWE-bench, solving 49% of the verified dataset which consists of 500 real-world GitHub issues. This demonstrates the impressive capabilities of the latest Anthropic model.

Amazon Q Developer is built on Amazon Bedrock, a fully managed service for building generative AI applications that offers a choice of high-performing foundation models (FMs) from Amazon and leading AI companies. Amazon Q uses multiple FMs, including FMs from Amazon, and routes tasks to the FM that is the best fit for the job. Amazon Q is constantly getting better, and we regularly change or refine the underlying models to improve performance and take advantage of the latest technologies, as we have latest version of Anthropic’s Claude 3.5 Sonnet launching just a week ago.

By powering the new inline chat capability with this cutting-edge Anthropic model, Amazon Q Developer is delivering an AI assistant that can help you save time, while tackling your most complex coding challenges with unparalleled capabilities. And with the seamless model updates handled behind the scenes, you can be confident that your experience will only continue to improve over time. Let’s take a moment to see how inline chat works.

Refactoring code

Let’s see the inline chat in action. Imagine that I have a class that displays messages on a web page. It started simple, but over time I have added a few variants to change the color, display warning messages, and display error messages. I don’t want to continue adding more and more variants, so I will ask Amazon Q Developer to refactor them. I select all four methods, and press ⌘ + I on Mac or Ctrl + I on Windows. Then, I prompt Q Developer to “refactor these into a single method with optional parameters for the color and message type.”

Animated gif showing four similar methods in VSCode. Inline chat refactors the methods into one with optional parameters. This is displayed as a diff and then merged.

As you can see in the previous video, Amazon Q Developer refactored my code into a single method. Note that Q is showing me which lines it will add, in green, and which lines it will remove, in red. I’m happy with this recommendation, so I will hit return to accept it. Q Developer then merges the changes into my code.

While I could have done this in the chat pane, I would have to copy the response, and merge it to my code manually. Inline chat returns a diff so I can see exactly which portions will be added and removed. Alternatively, I could have used inline suggestions to generate a new method. However, I would have been left to clean up the old methods manually. The new inline chat feature excels at updating code in place.

Adding documentation

I’ll demonstrate another practical use of inline chat. Recently, I was working on a complex data processing algorithm that I had written some time ago. While the code functioned correctly, it lacked proper documentation. Recognizing that this could hinder future maintenance and comprehension by the team, I decided to add comprehensive documentation.

Animated gif showing a python function in VSCode. Inline chat is used to ask Q to add comments. This is displayed as a diff and then merged.

I selected the entire function and activated the inline chat using ⌘ + I on Mac (or Ctrl + I on Windows). In the chat interface, I entered the prompt “Add documentation including descriptive comments throughout the code.” Q Developer swiftly analyzed the code and generated appropriate documentation. The suggestions appeared with new text highlighted in green, indicating additions.

Amazon Q Developer created a detailed comment block at the beginning of the script, including parameter descriptions and return value information. It also added inline comments throughout, explaining complex logic and calculations. After a thorough review of the suggested documentation, I accepted the changes by hitting return or clicking on “Accept”. Q Developer then integrated the new documentation seamlessly into the existing code.

This feature proves particularly useful when dealing with legacy code or preparing for new team members to join a project. It helps maintain consistency in documentation style across the codebase and significantly reduces the time required compared to manual documentation. The resulting well-documented code is self-explanatory, which can streamline the development process. Inline chat has made it more efficient to keep codebases well-documented and maintainable.

Conclusion

With the introduction of inline chat, Amazon Q Developer has taken the next leap in AI-powered development, combining the best of both worlds – combining the benefits of in-IDE chat with the ability to directly update code. This new capability, powered by Anthropic’s latest Claude 3.5 Sonnet, empowers developers to tackle complex coding challenges efficiently. Whether it’s generating new features, refactoring existing code, or adding comprehensive documentation, inline chat streamlines the workflow, eliminating the need to switch between separate chat and editor windows. By continuously integrating the latest advancements in AI language models, Amazon Q Developer ensures that developers always have access to the most advanced and capable generative AI-powered assistant, handling the undifferentiated heavy lifting and allowing them to focus on what they do best – writing high-quality, innovative code.

You can try it out today by updating or installing your Amazon Q Developer extension on VS Code or JetBrains. This update will help you unleash your productivity right in your IDE.

How to Create a Big Yellow Taxi to Help Protect Amazon WorkMail

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-create-a-big-yellow-taxi-to-help-protect-amazon-workmail/

Your Organization’s Email May Be at Risk: Lessons from the Microsoft Exchange Online Intrusion and Guidance to Ensure Better Protection.

The recent compromise of Microsoft Exchange Online accounts serves as a stark reminder of the critical need for robust email security measures. In this high-profile incident, bad actors were able to bypass security controls and gain access to email accounts across multiple organizations. As the Cyber Safety Review Board’s investigation revealed, the successful intrusion occurred due to inadequate security controls, including insufficient audit logging and alert systems. Fortunately, the intrusion was detected by the U.S. State Department’s “Big Yellow Taxi” proactive monitoring and alert system.

This post explains how to implement a similar “Big Yellow Taxi” alert system for your Amazon WorkMail  environment using WorkMail’s audit logging capabilities. This blog will use several AWS services, including Amazon CloudWatch and Amazon Simple Notification Service (SNS), to send email alerts when unauthorized, failed access attempts are detected. This simple, near real-time alerting system provides your email and security administrators the information they need to investigate and address any potential security threats to protect your organization’s sensitive email communications.

The Microsoft Exchange Online Intrusion: A Stark Reminder

The recent Cyber Safety Review Board (CSRB) findings on the Summer 2023 Microsoft Exchange Online intrusion are deeply concerning for any organization using a cloud-hosted inbox service, including Amazon WorkMail. In this incident, the intruders leveraged a stolen Microsoft Services Account (MSA) signing key to forge authentication tokens, bypassing security controls and gaining access to the email accounts of high-profile government officials in multiple organizations. Critically, it was only the U.S. State Department’s proactive monitoring of the MailItemsAccessed log that first detected the intrusion which initiated a custom “Big Yellow Taxi” alert.

This scenario serves as a stark reminder that the most sophisticated email platforms can be vulnerable to determined threat actors. WorkMail is built on top of Amazon’s Simple Email Service (SES) and the core security architecture and practices of AWS, which help to ensure the security of your WorkMail Organization. However, it is up to you to ensure organization’s sensitive communications are not put at risk by following the best practice security measures called out in the documentation and blog posts, including:

  • Take proper security measures, per the Amazon WorkMail documentation.
  • Turn on WorkMail audit logging as described in this AWS blog.
  • Periodically remind your users to practice good cybersecurity. They should never share usernames or passwords, and be careful not to leave private information on public computers.

As a reminder, while AWS is responsible for the security of the underlying AWS cloud infrastructure, the responsibility for securing your email data and access controls within Amazon WorkMail falls squarely on your organization, as outlined in AWS’s Shared Responsibility Model.

Securing and Monitoring Amazon WorkMail

Before you can create a custom “Big Yellow Taxi” alert you must first set up your Amazon WorkMail organization and have configured both Event Logging and Audit Logging. These steps are described in the Amazon WorkMail documentation.

Once logging is set up, the steps below will guide you in the creation of a “Big Yellow Taxi” alerting system that uses a CloudWatch Subscription Filter to continuously scan the WorkMail logs. Whenever the filter detects an Authentication log entry containing the phrase "access_granted:false" (indicating a failed login attempt), the CloudWatch Subscription Filter will automatically invoke an AWS Lambda function. The Lambda function then extracts the relevant details from the log data, constructs an alert notification, and dispatches it to an Amazon SNS topic configured to send email.

This simple, yet powerful alerting system helps ensure you’re alerted to failed login attempts in a timely manner, giving you the information you need to dig deeper to ensure your WorkMail Organization is not being targeted by a malicious actor. Let’s get started!

Building a WorkMail Monitoring & Alerting Mechanism

This sample solution uses a CloudWatch Subscription Filter (video) to monitor the WorkMail audit logs. The filter will scan the logs for a specific pattern that indicates a user has attempted to log in using an unauthorized method. For example, if you explicitly deny the use of the IMAP protocol in your WorkMail organization via Access control rules, the filter will detect such an attempt, invoking a Lambda function. This function will then construct an alert notification and dispatch it to an SNS topic configured to send an email, typically to your security admin’s mailing list.

  1. When a message from the Log Group contains “access_granted:false” (indicating a match with the Access Control rule), the subscription filter will deliver the message to the AWS Lambda function.
  2. The Lambda function extracts the user name and organization details from the ID received from CloudWatch.
  3. The Lambda function concatenates this information and sends it to an SNS topic
  4. The SNS topic delivers a notification email message to an admin’s mailbox.
    (note – the dashed lines in the diagram represent optional components that are not addressed in this specific scenario.)

Walkthrough

This blog will walk you thru the following steps in your AWS account needed to create your own “big-yellow-taxi” alerts from your WorkMail Audit Logs (perform all steps in the same AWS region as your WorkMail Organization):

  1. Create an Amazon SNS topic and configure it to send email notifications to your email and security administrators when the alert condition is matched
  2. Create an IAM Policy
  3. Create an IAM Role to allow a custom Lambda to invoke SNS and WorkMail
  4. Create a custom AWS Lambda function that will be invoked by the CloudWatch Subscription Filter. This function will do the following::
    1. Extract the relevant details from the WorkMail alert logs data, such as the user account, IP address, and timestamp of the failed login attempt.
    2. Construct a concise, informative alert notification.
    3. Publish the alert notification to an Amazon SNS topic.
  5. Test the “big-yellow-taxi” alert by attempting unauthorized access attempts to your Amazon WorkMail environment.

Prerequisites

  • An AWS account with permissions to create / modify WorkMail, SNS, Lambda and IAM.
    • You’ll need your AWS Account ID, which you can get from the AWS console or the AWS CLI.
  • A fully set up Amazon WorkMail Organization.
    • You’ll need your WorkMail Organization’s ARN, which you can get from the AWS console or the AWS CLI.
  • Your WorkMail Organization must be configured to deliver Access Control logs to CloudWatch.

Step 1 – Create Simple Notification Service (SNS) Topic

Create an SNS topic and configure it to send email notifications when a login occurs with an unauthorized method.

  1. Open the AWS SNS Console in the same region as your WorkMail Organization
    1. Click Create topic
    2. Name: workmail-yellow-taxi
    3. Create topic
  2. Create Subscription.
    1. Select the Topic you created in the step above.
    2. Select email as the protocol, and enter an email address to which you have access (you can modify this later if desired)
    3. Create subscription.
    4. Check your email and confirm the SNS subscription (this may take a minute and you may need to check your spam folder)
  3. Make note of the SNS Topic ARN shown in the SNS topic Details panel, as you’ll need it in the next step.

Step 2 – Create an IAM policy

  1. Open the AWS IAM Console
  2. Create new IAM policy
    1. Name: workmail-yellow-taxi
    2. Copy (below), edit with your AWS ID, SNS arn and WorkMail Organization arn, and paste the updated JSON into the permission policy editor.
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"workmail:DescribeOrganization",
"sns:Publish",
"workmail:DescribeUser"
],
"Resource": [
"arn:aws:sns:<aws-region-x>:000000000000:workmail-yellow-taxi",
"arn:aws:workmail:<aws-region-x>:000000000000:organization/m-03fdc11b0c8c42d699dfc65fbb683b6a"
]
}
]
}

Step 3 – Create an IAM role

  1. Open the AWS IAM Console
    1. Create a new Role
    2. Select AWS service
      1. Use Case – choose Lambda
      2. Search for, and add “AWSLambdaBasicExecutionRole
      3. Role Name: yellow-taxi-lambda
      4. Edit & Add permissions – Search for, and add:
        1. workmail-yellow-taxi
    3. Create role

Step 4 – Create an IAM role

  1. Go to the AWS Lambda console (in the same region as your WorkMail Organization).
  2. In the Services Search field, type Lambda
  3. Click Create function
    1. Author from scratch
    2. Function name: WorkMailAudit
    3. Runtime: Python3.12
    4. Architecture: x86_64
    5. Permissions: select the role (created above) yellow-taxi-lambda.
    6. Create function
  4. Copy the Lambda code (below) and paste it into the lambda_function editor (under the Lambda’s Code tab):
import json
import base64
import zlib
import boto3
from botocore.exceptions import ClientError
import re
import os
 
topic_arn = os.environ['SNS_ARN']
sns = boto3.client('sns')
workmail = boto3.client('workmail')
 
def send_sns_message(topic_arn, message):
 
    try:
        # Send Message
        response = sns.publish(
            TopicArn=topic_arn,
            Message=str(message)
        )
        print(f"Message delivered sucessfully! Message ID: {response['MessageId']}")
    except ClientError as e:
        print(f"Error to send message: {e}")
 
def get_workmail_user_and_organization_names(organization_id, user_id):
   
    try:
        # Getting user name
        user_response = workmail.describe_user(OrganizationId=organization_id, UserId=user_id)
        user_name = user_response['Name']
        
        # Getting organization name
        org_response = workmail.describe_organization(OrganizationId=organization_id.split('/')[-1])
        organization_name = org_response['Alias']
        
        return user_name, organization_name
    except Exception as e:
        print(f"Error to get information : {e}")
        return None, None
 
def lambda_handler(event, context):
   
    #uncode and decompress CloudWatch function
    workmail_log = zlib.decompress(base64.b64decode(event["awslogs"]["data"]), 16 + zlib.MAX_WBITS).decode('utf-8')
    log_json = json.loads(workmail_log)
   
    for log_event in log_json["logEvents"]:
        log_message = json.loads(log_event["message"])
        organization_arn = log_message["organization_arn"]
        
        # Regex to get Organization Id from log
        organization_id = (re.search(r'[^/]+$', organization_arn)).group(0)
        user_id = log_message["user_id"]
        
        # Get username from WorkMail Organization
        user_name, organization_name = get_workmail_user_and_organization_names(organization_id, user_id)
        payload = {
            "User": user_name,
            "Organization": organization_name,
            "Protocol": log_message["protocol"],
            "Source IP": log_message["source_ip"],
            "Event": "Login attempt using unauthorized method"
        }
 
    send_sns_message(topic_arn, payload)
   
    return {
        'statusCode': 200
    }
  1. Click the Deploy button
  2. Click the Configuration tab, click Environment Variables (left menu) and click edit
    Key = SNS_ARN | Value = <the arn of the SNS topic you created earlier)
  3. Click Save

Step 5 – Verify the CloudWatch log you’ve configured in WorkMail

  1. Open the AWS CloudWatch console for your WorkMail Organization
  2. Click Logging settings
  3. Click the Audit log settings tab
    1. Make note of the Amazon CloudWatch Log destination for the Log deliveries – Access Control logs

4. Create an Access Control rule in WorkMail create a rule to deny the use of the IMAP protocol (see below):

    • Describe the rule: DENY_IMAP
    • Effect: Deny
    • Apply the rule to requests that use IMAP
    • Create the rule

5. Create the CloudWatch subscription filter:

  • Open the AWS CloudWatch console for your WorkMail Organization
  • Click Log groups and select: WorkMail-yellow-taxi
  • Click the subscription filter tab and Create a new Lambda subscription filter
    • Select the Lambda: WorkMailAudit
    • Log format: JSON
    • Subscription filter pattern: "\"access_granted\":false"
    • subscription filter name: workmail-yellow-taxi-filter
  • Click Start streaming

Congratulations, you’ve set up your own Yellow-Taxi alert to send you an email if someone tries to login to a WorkMail account using a denied protocol (IMAP in this example).

Testing your Big Yellow Taxi alert

To test the new rule using the AWS CLI (you will need a valid WorkMail user’s login and password), you can attempt to login using IMAP, whcih you denied above.

  1. Copy, edit & paste the openssl command into the AWS CLI (note – the imap address region needs to match your WorkMail region) to attempt a login using the prohibited IMAP protocol:

openssl s_client --connect imap.mail.us-west-2.awsapps.com:993

2. You’ll get the following back in the terminal:

OK [CAPABILITY IMAP4rev1 SASL-IR LOGIN-REFERRALS ENABLE IDLE LITERAL+ AUTH=PLAIN] Amazon WorkMail IMAP Proxy

3. Type the LOGIN command using a valid WorkMail user’s email address and password

? LOGIN [email protected] user's_password

4. You’ll be denied access (because IMAP is set for “deny”)

Shortly after your failed attempt to login, you’ll receive an email at the address specified in the SNS topic from AmazonSNS with details about the failed attempt similar to the message shown below:

Conclusion

Just as the U.S. State Department’s “Big Yellow Taxi” custom alert rule proved instrumental in detecting the initial signs of the Microsoft Exchange Online compromise, this simple yet effective monitoring and alerting system will help ensure your organization receives timely notice of failed login attempts. These alerts allow you to investigate and respond to potential threats quickly. By actively monitoring your WorkMail environment, you will able to protect your organization’s sensitive email communications against this type of intrusion incident.

Next Steps

The time to act is now to ensure your WorkMail instance is fortified against emerging threats. Following the guidance in this blog post helps you strengthen your WorkMail security posture and protect your sensitive communications from malicious actors.

By implementing the CloudWatch Subscription Filter and AWS Lambda-based alerting system, you can establish a proactive “Big Yellow Taxi” monitoring solution for your Amazon WorkMail environment. This will provide your organization with the necessary visibility and alerting capabilities to quickly detect and respond to unauthorized access attempts, helping to safeguard your sensitive email data.

If you have questions or comments, join the AWS Community Forums to ask questions, share experiences, and learn from other AWS users who have implemented similar solutions for secure email sending from their web applications.

To learn more about Amazon WorkMail, or to create a no-cost 30-day test organization, see Amazon WorkMail.

About the Authors

Miguel

Luis Miguel Flores dos Santos

Miguel is a Solutions Architect at AWS, boasting over a decade of expertise in solution architecture, encompassing both on-premises and cloud solutions. His focus lies on resilience, performance, and automation. Currently, he is delving into serverless computing. In his leisure time, he enjoys reading, riding motorcycles, and spending quality time with family and friends.

Andy Wong

Andy Wong

Andy Wong is a Sr. Product Manager with the Amazon WorkMail team. He has 10 years of diverse experience in supporting enterprise customers and scaling start-up companies across different industries. Andy’s favorite activities outside of technology are soccer, tennis and free-diving.

Zip

Zip

Zip is a Sr. Specialist Solutions Architect at AWS, working with Amazon Pinpoint and Simple Email Service and WorkMail. Outside of work he enjoys time with his family, cooking, mountain biking, boating, learning and beach plogging.

Войната на бъдещето

Post Syndicated from Григор original http://www.gatchev.info/blog/?p=2651

Мисля си – човечеството върви към Трета световна война. На която сегашната война в Украйна е просто Судети.

Не е нужно човек да е историк, за да види, че ситуацията е аналогична с тази преди Първата и Втората световни. Старите световни сили са запуснали военната си мощ с убеждението, че мирът е завинаги. А едни нови сили се въоръжават бързо и апетитите им да господаруват над света или части от него вече са големи. И където им се позволи да „ядат“ – да си откъснат парчета от други страни – апетитите им растат.

Ситуацията обаче е различна от класическата с важен нюанс. Повечето от „новите сили“ хич не са нови, нов е само апетитът им. (На Русия и апетитът ѝ не е нов, но тя за последните стотина години си е бясното куче на света.) Разделението всъщност е не между стари колониални сили и нови сили с мерак за колонии. То е между демокрации и диктатури.

Базата му е общото разбиране на диктатурите, че демокрациите са смъртна заплаха за тях не с това, че ще ги унищожат с военна сила, а с това, че просто съществуват. И с това доказват, че обикновените хора могат да са не нечий добитък, роби или крепостни, а свободни и господари на съдбата си. И че тогава живеят по-добре и по-щастливо, постигат повече и са по-силни. И съграждат държави, които напредват по-бързо и плодотворно от диктатурите…

Диктатурите наричат себе си „капитализъм“, „комунизъм“ и подобни – но знаят отлично, че са всъщност феодализъм с робовладелски елементи. Наричането на феодалите „олигарси“, или това на робовладелците „партийни секретари“ не го променя, само се опитва да го прикрие, то е поредната им лъжа. Не е луд който лъже, луд е който му вярва, нали? Е, при тях луди във върхушката няма, ще са опасни за адекватните там. Както примерно у нас в Политбюро беше немислимо да има вярващ комунист. Видеше ли как живеят, щеше да разбере, че истинските чорбаджии и подтисници в България са именно те, и щеше да тръгне да вдига революция срещу тях…

Затова разбират отлично, че съществуването на демокрациите е смърт за тях. Че каквито и планини от лъжи да трупат те, рано или късно „добитъкът“ им ще научи истината и ще ги събори. Че няма да го спре дори най-любимата лъжа на диктатурите – „обратното е, свободата е тук а робството там, процъфтяването е тук а загниването там…“ Че единствената им надежда е пълното унищожаване на всички демокрации. Само тогава може да бъде унищожена самата идея за свобода, по оруеловски. Само тогава обикновените хора могат да бъдат държани роби завинаги.

(Всъщност и тогава не може. Рим го направи могъщ свободата на гражданите му. Тя създаде такава база, че дори след като се превърна в империя, Рим контролира екумена си с векове. Да, след като рухна дойде Средновековието, наричано на повечето езици „време на мрака“. Но и в него забутан остров на края на екумена в един момент прие Харта за правата и свободите. Съгради на нейна база малко по-свободно от околните общества. А то направи индустриална революция и превърна страната си в световна империя. Която отстъпи от тези позиции чак след като беше надконкурирана от други, взели нейната свобода и я умножили, и станали още по-могъщи… И демокрацията се възроди, още по-силна отпреди.

Преди повече от 20 години бях сънувал един сън – ето извадка от него:

Често търговци на омраза или страх ще обявяват бъдещето за смърт на настоящето, и ще го забраняват, забравили, че смъртта и животът са едно, или уплашени от това. Често ще успяват да превземат сърца и умове, и да заслепяват взорове. Но бъдещето е по-мъдро от настоящето, и след миг или епохи ще намира начин да ги превърне в минало. И ще продължаваме напред, разбрали, че бъдеще дава единият избор – другият дава минало завинаги. И припомнили си, че сме деца не на калта, а на звездите.)

Особеността на това разбиране е, че го споделят не само диктатори и сатрапи. Споделят го и „редови“ психопати с усещането, че само те са хора, а другите са играчки за тях. И отпадъци на еволюцията, уплашени че губят състезанието за бъдещето. И садисти, готови да целуват ботушите на господари срещу правото да измъчват робите… Накратко – всички, за които най-скъпоценната свобода е да отнемат свободата на другите. Които ненавиждат свободите на другите, но за своите и най-вече за тази пищят, че им се ограничава.

Затова всички те имат общ интерес във войната, която вече се води. (И на която бъдеща Трета световна между демокрациите и диктатурите е само един от многото аспекти.) И диктатурите знаят това отлично, и търсят съюз и взаимодействие с местните психопати, садисти и отпадъци на еволюцията в демокрациите. Или дори просто ги подпомагат, като начин да пренесат войната си срещу „врага“ на негов терен. (Някой учуден защо Русия подкрепя Тръмп?)

Имат интерес и да манипулират глупавите и лековерните, за да ги превърнат в „полезни идиоти“ (терминът е на ГРУ) и да ги използват за пушечно месо във войната си. И благодарение на Русия имат и технологии за социално инженерство, които да им помагат в това. Затова и в днешните времена идиотът винаги е опасен за адекватните – шансът някой психопат да е успял да му хване конците и да го марионетства да ти навреди е голям.

Така че дойде ли бъдещата световна война, диктатурите ще имат своите помощници сред демокрациите. Тези хора, които за нормалните са отрепки, опасни идиоти, психопати, садисти и подобни. Рафиниран вариант на деветосептемврийците от 1944 г. – вече без идеалисти, освен в ролята на пушечно месо за спешно похарчване. И без идеологии за „човечност“, „добър живот за работниците“ и подобни. Озъбен и безмилостен пещерен, психопатски консерватизъм. Не този, който в нито помен отъздиша по доброто старо време и се оплаква, че младите са невъзпитани – този, който получава оргазъм от садистично избиване на нежелаещи да бъдат роби.

Ето това е войната, която ни очаква. Това са страните, които ще воюват в нея. Това е, което очаква обикновените хора където стъпят диктатурите. И това са тези, които ще ги предадат отвътре.

Предупреденият е въоръжен.

Watermark for LLM-Generated Text

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/watermark-for-llm-generated-text.html

Researchers at Google have developed a watermark for LLM-generated text. The basics are pretty obvious: the LLM chooses between tokens partly based on a cryptographic key, and someone with knowledge of the key can detect those choices. What makes this hard is (1) how much text is required for the watermark to work, and (2) how robust the watermark is to post-generation editing. Google’s version looks pretty good: it’s detectable in text as small as 200 tokens.

Are Automatic License Plate Scanners Constitutional?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/are-automatic-license-plate-scanners-constitutional.html

An advocacy groups is filing a Fourth Amendment challenge against automatic license plate readers.

“The City of Norfolk, Virginia, has installed a network of cameras that make it functionally impossible for people to drive anywhere without having their movements tracked, photographed, and stored in an AI-assisted database that enables the warrantless surveillance of their every move. This civil rights lawsuit seeks to end this dragnet surveillance program,” the lawsuit notes. “In Norfolk, no one can escape the government’s 172 unblinking eyes,” it continues, referring to the 172 Flock cameras currently operational in Norfolk. The Fourth Amendment protects against unreasonable searches and seizures and has been ruled in many cases to protect against warrantless government surveillance, and the lawsuit specifically says Norfolk’s installation violates that.”

Introducing the new Amazon Q Developer experience in AWS Lambda

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/introducing-the-new-amazon-q-developer-experience-in-aws-lambda/

AWS Lambda recently announced a new code editor based on Code-OSS. Like the previous version, the new editor includes Amazon Q Developer. Amazon Q Developer is a generative AI-powered assistant for software development that can help you build and debug Lambda functions more quickly. In this post, I provide an overview of Amazon Q Developer’s integration into the new built-in code editor.

Introduction

AWS Lambda first supported Amazon Q Developer in 2022 (previously known as Amazon CodeWhisperer). While Q Developer has added many features since 2022, the experience in the Lambda editor has remained mostly unchanged until recently. For example, the quality and length of recommendations has increased significantly over the past two years. The original blog post announcing support for Q Developer in the Lambda editor (then called CodeWhisperer) used a series of prompts such as “upload a file to an S3 bucket” or “send a notification using SNS” to incrementally build a Lambda function. While that was impressive at the time, Q Developer can now accept much longer and more complex prompts. For example, I asked Q Developer to create an image moderation function with the following comment. This comment will result in about seventy lines of Python code, including whitespace.

This function moderates images uploaded to S3. It is invoked by an S3 event notification when a new image is uploaded. First, it calls Rekognition image moderation. It also uses Rekognition to extract text from the image, and uses Comprehend to check for toxic content. Finally, it sends a message to the SQS queue identified in the env var QUEUE_URL if the image was moderated or if it contained toxic content. The env var MIN_SCORE allows configuration of the confidence score used as the threshold for both moderation and toxicity.

While I can use this comment in both the old and new editor, the experience in the new editor has significantly improved. Note that in the following image of the old editor, I can only see the first eight lines of the suggestion in a popup. I have to scroll to review the remaining 62 lines of code. The old editor experience did not anticipate that Q Developer would someday return 70 lines, or more, in a single response.

Screenshot of the AWS Lambda code editor showing a Python function for image moderation. The code includes comments describing the function's purpose and a popup with initial import statements and AWS service client initializations.

The experience in the new editor is much improved as shown in the following image. I can preview the entire suggestion in-line with my code, up to the size of my screen. This makes it much easier to evaluate the suggestion before deciding to accept or decline it.

Screenshot of the AWS Lambda code editor showing a Python function for image moderation. The code includes comments describing the function's purpose and a popup with initial import statements and AWS service client initializations.

Now that you have seen the new editor in action, let’s discuss how to configure and use it.

Inline completions in Lambda

Q Developer can provide you with code recommendations in real time. As you write code, Q Developer automatically generates suggestions based on your existing code and comments. Before I can use Q Developer in the Lambda console, I must first configure it as described in Using Amazon Q Developer with AWS Lambda. With that done, I am ready to start with a simple example.

While I love Python, I often find myself working with a dictionary object without knowledge of its structure. As a result, I waste time reading the documentation searching for the names of various keys. In Lambda, the event object is passed as a dictionary. In addition, each event type has a different structure. Q Developer can save me countless hours of reading documentation to find the structure of each event.

As an example, imagine that I have created a function that can be triggered by Amazon API Gateway, Application Load Balancer, and AWS AppSync. I need to get the IP address of the client that invoked my function. While this is available in the X-Forwarded-For header, the location and format of the header in the dictionary is subtly different in each event type. Q Developer can save me a trip to the documentation.

In the example below, Q Developer is making the correct suggestion for API Gateway based on the contextual clues in my file. Specifically, the comments on lines one and three. When I hit enter at the end of line three, Q Developer uses the context to recommend the code on line four. Note that it correctly recommends X-Forwarded-For with capitals for an API Gateway event.

Screenshot of the AWS Lambda code editor showing a Python function. Q is suggesting code to extract the x-forwarded-for header.

However, in the next example, the comment on line one now mentions an Application Load Balancer. Note that Q Developer correctly recommends x-forwarded-for in lower-case for an Application Load Balancer event.

Screenshot of the AWS Lambda code editor showing a Python function. Q is suggesting code to extract the x-forwarded-for header.

That trivial example just saved me a trip to the documentation that would have taken three to five minutes. If I can do that a few times every hour, it has a huge impact on my productivity and focus due to less context switching.

While the in-line completion experience is greatly improved in the new editor, Q Developer supports other capabilities in the Lambda console that I do not want to overlook. Let’s take a moment to review chat and troubleshooting, which are unchanged with the release of the new editor.

Chat in the Lambda console

Q Developer supports chat in the Lambda console. I can use this to ask questions rather than reading through the documentation. Returning to my original example, the image moderation function, remember that my function expects two environment variables, QUEUE_URL andMIN_SCORE.Imagine that I do not know how to configure an environment variable in the Lambda console. In the following example, I chat with Q Developer to ask for help.

Screenshot of the AWS Lambda code showing the chat pane. Q is providing instructoins for creating an env var in Lambda.

Note that the response is aware of my position in the console. Q Developer says “It looks like you’re already in the function design.” Q Developer not only saves me a trip to the documentation, but it tailors the suggestion to my current position so I do not have to read unnecessary instructions. I will follow Q Developer’s instructions to configure the two required environment variables as shown below.

Screenshot of the AWS Lambda env var with the two variables created.

You can see how chat is able to help keep me on task and in a state of flow. Next, I will show you how Q Developer can help you troubleshoot issues in the console.

Troubleshooting in the Lambda console

With the environment variables configured, I am ready to test my function. However, when I run a test, I get an error message as shown in the following image. Note the “Diagnose with Amazon Q” button. Q Developer noticed that I am having issues, and is offering to help.

A Lambda error with the “Diagnose with Amazon Q” button shown

If I select the “Diagnose with Amazon Q” button, Q Developer will analyze the error. In the example below, you can see that it has identified that “the Lambda function is unable to access an object in S3.” Of course! I never granted the Lambda function permission to access the Amazon Simple Storage Service (Amazon S3) bucket.

Amazon Q troubleshooting providing Analysis and resolution of the issue.

I could go back to the chat pane I used earlier and ask Q Developer how to add permissions. However, notice that it already provides set-by-step instructions to fix the issue. So, I don’t even need to use the chat. Once I fix the permissions, my function is working as expected. Q Developer has saved me time and made me much more productive.

Cleanup

If you have been following along and deployed a Lambda function, please remember to delete it.

Conclusion

The new AWS Lambda built-in editor experience greatly improves the Q Developer inline suggestion experience for Lamba. This new editor, combined with the existing chat and troubleshooting capabilities can significantly improve your productivity. To learn more read Getting started with Amazon Q Developer and Using Amazon Q Developer with AWS Lambda.

No, The Chinese Have Not Broken Modern Encryption Systems with a Quantum Computer

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/no-the-chinese-have-not-broken-modern-encryption-systems-with-a-quantum-computer.html

The headline is pretty scary: “China’s Quantum Computer Scientists Crack Military-Grade Encryption.”

No, it’s not true.

This debunking saved me the trouble of writing one. It all seems to have come from this news article, which wasn’t bad but was taken widely out of proportion.

Cryptography is safe, and will be for a long time

EDITED TO ADD (11/3): Really good explainer from Dan Goodin.

AI and the SEC Whistleblower Program

Post Syndicated from B. Schneier original https://www.schneier.com/blog/archives/2024/10/ai-and-the-sec-whistleblower-program.html

Tax farming is the practice of licensing tax collection to private contractors. Used heavily in ancient Rome, it’s largely fallen out of practice because of the obvious conflict of interest between the state and the contractor. Because tax farmers are primarily interested in short-term revenue, they have no problem abusing taxpayers and making things worse for them in the long term. Today, the U.S. Securities and Exchange Commission (SEC) is engaged in a modern-day version of tax farming. And the potential for abuse will grow when the farmers start using artificial intelligence.

In 2009, after Bernie Madoff’s $65 billion Ponzi scheme was exposed, Congress authorized the SEC to award bounties from civil penalties recovered from securities law violators. It worked in a big way. In 2012, when the program started, the agency received more than 3,000 tips. By 2020, it had more than doubled, and it more than doubled again by 2023. The SEC now receives more than 50 tips per day, and the program has paid out a staggering $2 billion in bounty awards. According to the agency’s 2023 financial report, the SEC paid out nearly $600 million to whistleblowers last year.

The appeal of the whistleblower program is that it alerts the SEC to violations it may not otherwise uncover, without any additional staff. And since payouts are a percentage of fines collected, it costs the government little to implement.

Unfortunately, the program has resulted in a new industry of private de facto regulatory enforcers. Legal scholar Alexander Platt has shown how the SEC’s whistleblower program has effectively privatized a huge portion of financial regulatory enforcement. There is a role for publicly sourced information in securities regulatory enforcement, just as there has been in litigation for antitrust and other areas of the law. But the SEC program, and a similar one at the U.S. Commodity Futures Trading Commission, has created a market distortion replete with perverse incentives. Like the tax farmers of history, the interests of the whistleblowers don’t match those of the government.

First, while the blockbuster awards paid out to whistleblowers draw attention to the SEC’s successes, they obscure the fact that its staffing level has slightly declined during a period of tremendous market growth. In one case, the SEC’s largest ever, it paid $279 million to an individual whistleblower. That single award was nearly one-third of the funding of the SEC’s entire enforcement division last year. Congress gets to pat itself on the back for spinning up a program that pays for itself (by law, the SEC awards 10 to 30 percent of their penalty collections over $1 million to qualifying whistleblowers), when it should be talking about whether or not it’s given the agency enough resources to fulfill its mission to “maintain fair, orderly, and efficient markets.”

Second, while the stated purpose of the whistleblower program is to incentivize individuals to come forward with information about potential violations of securities law, this hasn’t actually led to increases in enforcement actions. Instead of legitimate whistleblowers bringing the most credible information to the SEC, the agency now seems to be deluged by tips that are not highly actionable.

But the biggest problem is that uncovering corporate malfeasance is now a legitimate business model, resulting in powerful firms and misaligned incentives. A single law practice led by former SEC assistant director Jordan Thomas captured about 20 percent of all the SEC’s whistleblower awards through 2022, at which point Thomas left to open up a new firm focused exclusively on whistleblowers. We can admire Thomas and his team’s impact on making those guilty of white-collar crimes pay, and also question whether hundreds of millions of dollars of penalties should be funneled through the hands of an SEC insider turned for-profit business mogul.

Whistleblower tips can be used as weapons of corporate warfare. SEC whistleblower complaints are not required to come from inside a company, or even to rely on insider information. They can be filed on the basis of public data, as long as the whistleblower brings original analysis. Companies might dig up dirt on their competitors and submit tips to the SEC. Ransomware groups have used the threat of SEC whistleblower tips as a tactic to pressure the companies they’ve infiltrated into paying ransoms.

The rise of whistleblower firms could lead to them taking particular “assignments” for a fee. Can a company hire one of these firms to investigate its competitors? Can an industry lobbying group under scrutiny (perhaps in cryptocurrencies) pay firms to look at other industries instead and tie up SEC resources? When a firm finds a potential regulatory violation, do they approach the company at fault and offer to cease their research for a “kill fee”? The lack of transparency and accountability of the program means that the whistleblowing firms can get away with practices like these, which would be wholly unacceptable if perpetrated by the SEC itself.

Whistleblowing firms can also use the information they uncover to guide market investments by activist short sellers. Since 2006, the investigative reporting site Sharesleuth claims to have tanked dozens of stocks and instigated at least eight SEC cases against companies in pharma, energy, logistics, and other industries, all after its investors shorted the stocks in question. More recently, a new investigative reporting site called Hunterbrook Media and partner hedge fund Hunterbrook Capital, have churned out 18 investigative reports in their first five months of operation and disclosed short sales and other actions alongside each. In at least one report, Hunterbrook says they filed an SEC whistleblower tip.

Short sellers carry an important disciplining function in markets. But combined with whistleblower awards, the same profit-hungry incentives can emerge. Properly staffed regulatory agencies don’t have the same potential pitfalls.

AI will affect every aspect of this dynamic. AI’s ability to extract information from large document troves will help whistleblowers provide more information to the SEC faster, lowering the bar for reporting potential violations and opening a floodgate of new tips. Right now, there is no cost to the whistleblower to report minor or frivolous claims; there is only cost to the SEC. While AI automation will also help SEC staff process tips more efficiently, it could exponentially increase the number of tips the agency has to deal with, further decreasing the efficiency of the program.

AI could be a triple windfall for those law firms engaged in this business: lowering their costs, increasing their scale, and increasing the SEC’s reliance on a few seasoned, trusted firms. The SEC already, as Platt documented, relies on a few firms to prioritize their investigative agenda. Experienced firms like Thomas’s might wield AI automation to the greatest advantage. SEC staff struggling to keep pace with tips might have less capacity to look beyond the ones seemingly pre-vetted by familiar sources.

But the real effects will be on the conflicts of interest between whistleblowing firms and the SEC. The ability to automate whistleblower reporting will open new competitive strategies that could disrupt business practices and market dynamics.

An AI-assisted data analyst could dig up potential violations faster, for a greater scale of competitor firms, and consider a greater scope of potential violations than any unassisted human could. The AI doesn’t have to be that smart to be effective here. Complaints are not required to be accurate; claims based on insufficient evidence could be filed against competitors, at scale.

Even more cynically, firms might use AI to help cover up their own violations. If a company can deluge the SEC with legitimate, if minor, tips about potential wrongdoing throughout the industry, it might lower the chances that the agency will get around to investigating the company’s own liabilities. Some companies might even use the strategy of submitting minor claims about their own conduct to obscure more significant claims the SEC might otherwise focus on.

Many of these ideas are not so new. There are decades of precedent for using algorithms to detect fraudulent financial activity, with lots of current-day application of the latest large language models and other AI tools. In 2019, legal scholar Dimitrios Kafteranis, research coordinator for the European Whistleblowing Institute, proposed using AI to automate corporate whistleblowing.

And not all the impacts specific to AI are bad. The most optimistic possible outcome is that AI will allow a broader base of potential tipsters to file, providing assistive support that levels the playing field for the little guy.

But more realistically, AI will supercharge the for-profit whistleblowing industry. The risks remain as long as submitting whistleblower complaints to the SEC is a viable business model. Like tax farming, the interests of the institutional whistleblower diverge from the interests of the state, and no amount of tweaking around the edges will make it otherwise.

Ultimately, AI is not the cause of or solution to the problems created by the runaway growth of the SEC whistleblower program. But it should give policymakers pause to consider the incentive structure that such programs create, and to reconsider the balance of public and private ownership of regulatory enforcement.

This essay was written with Nathan Sanders, and originally appeared in The American Prospect.

Justice Department Indicts Tech CEO for Falsifying Security Certifications

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/justice-department-indicts-tech-ceo-for-falsifying-security-certifications.html

The Wall Street Journal is reporting that the CEO of a still unnamed company has been indicted for creating a fake auditing company to falsify security certifications in order to win government business.

Automating multi-AZ high availability for WebLogic administration server with DNS: Part 2

Post Syndicated from Robin Geddes original https://aws.amazon.com/blogs/architecture/automating-multi-az-high-availability-for-weblogic-administration-server-with-dns-part-2/

In Part 1 of this series, we used a floating virtual IP (VIP) to achieve hands-off high availability (HA) of WebLogic Admin Server. In Part 2, we’ll achieve an arguably superior solution using Domain Name System (DNS) resolution.

Using a DNS to resolve the address for WebLogic admin server

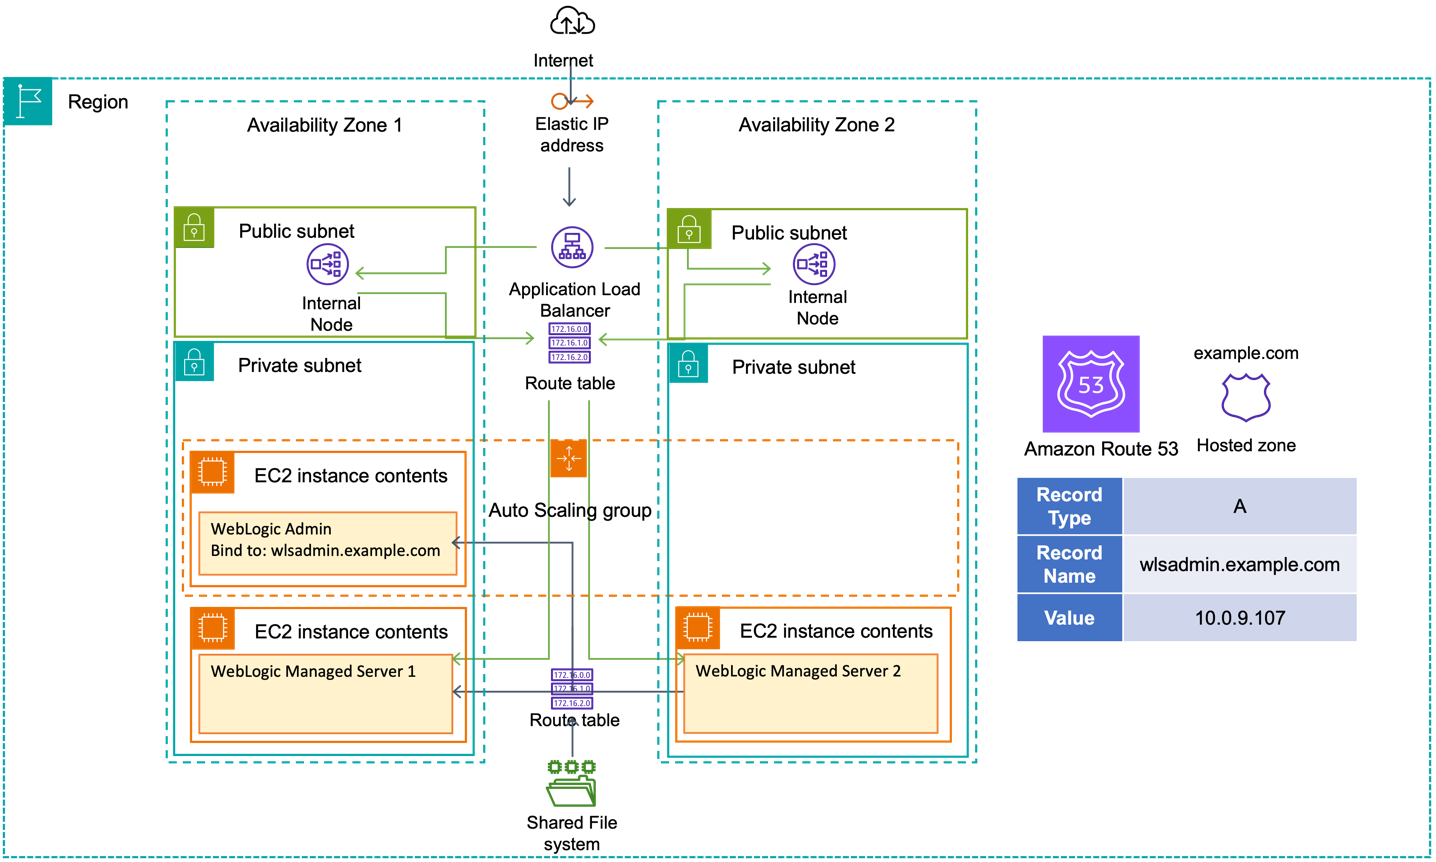
Let’s look at the reference WebLogic deployment architecture on AWS shown in Figure 1.

Reference WebLogic deployment with multi-AZ admin HA capability

Figure 1. Reference WebLogic deployment with multi-AZ admin HA capability

This solution comes in two parts:

  • Configure the environment to use DNS to locate the admin server.
  • Create a mechanism to automatically update the DNS entry when the admin server is launched.

Environment configuration

A WebLogic domain resides in private subnets of a Virtual Private Cloud (VPC). The admin server resides in one of the private subnets on its own Amazon Elastic Compute Cloud (Amazon EC2) instance. In this scenario, the admin server is bound to the private IP address of the EC2 host associated with a hostname/DNS record (configured in Amazon Route53).

We deploy WebLogic in multi-Availability Zone (multi-AZ) active-active stretch architecture. For this simple example, there is only one WebLogic domain and one admin server. To meet this requirement, we:

  1. create an EC2 launch template for the admin server, and then
  2. associate the launch template to an Amazon EC2 Auto Scaling group named wlsadmin-asg with min, max, and desired capacity of 1. Note we will need the group name later.

The Auto Scaling group detects EC2 and Availability Zone degradation and launches a new instance – in a different AZ if the current one becomes unavailable.

To enable access, we create two route tables: one for the private subnets, and the other for public subnets.

Next, we use the Amazon Route 53 DNS service to abstract the IPv4 address of the WebLogic admin server:

  • Create a private hosted zone in Amazon Route 53; in this example, we use example.com.
  • Create an A record for the admin server; in this example, example.com, pointing to the IP address of the EC2 instance hosting the admin server. Set the TTL to 60 seconds so the managed servers’ DNS records will be propagated before the admin server has finished starting.
  • Note the ID of the hosted zone, it will be required later in two places: to create an IAM role with permissions to update the DNS A record, and as an environment variable for an AWS Lambda function to perform the update.

We then update the WebLogic domain configuration and set the WebLogic Admin server listen address to the DNS name we chose. In this example, we set the line of WebLogic Admin server configuration to <listen-address>wlsadmin.example.com</listen-address> in WebLogic domain configuration file $DOMAIN_HOME/config/config.xml.

Automatically updating the DNS A record upon admin server launch

On-premises, it would often be a cultural anathema to update a DNS record as part of a server’s lifecycle. Operations that cut across team boundaries and responsibilities can be difficult to orchestrate. In the cloud, we have tools and a security model to enable such operations.

There are several approaches for this, and it is important to understand the patterns we prototyped and why they were rejected before we describe our recommended implementation pattern:

  • Rejected Option 1 – Simple: The user data script makes an API call to update the A record (with suitable IAM instance policy). However, a compromised server could update that A record for nefarious means; hence, we reject this option.
  • Rejected Option 2 – Better: The user data script calls a Lambda function to update the A record and include suitable checks to prevent misuse of the A record, such as setting it to a public address. This still requires granting permission for instance to call the lambda function and determining the correct logic to validate the IP address.
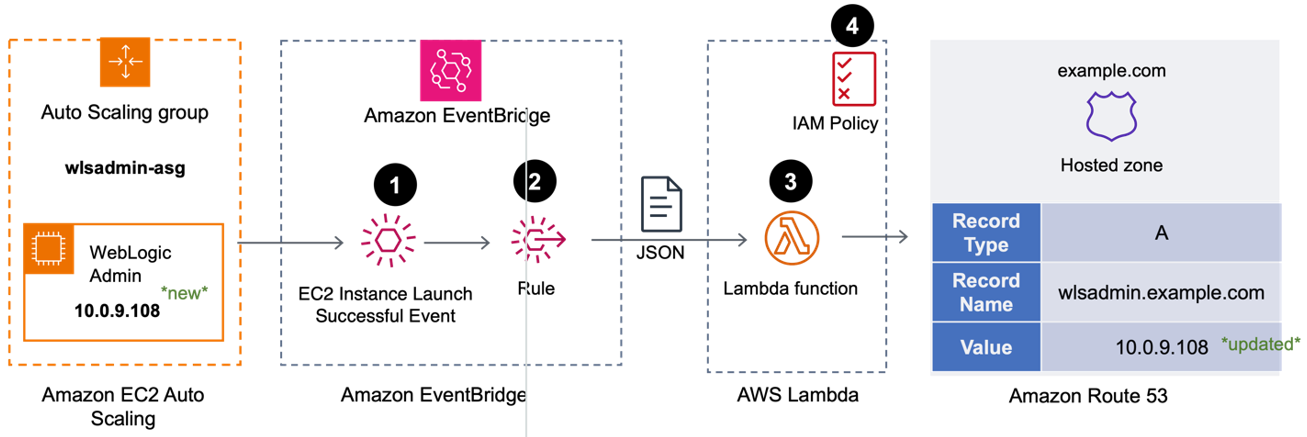
  • Accepted Option 3 – Best: We do not grant the EC2 instance any additional permission to update the DNS A Record. We rely on the event lifecycle of the Auto Scaling group as shown in Figure 2.
Triggering the DNS A record update from EventBridge using Lambda

Figure 2. Triggering the DNS A record update from EventBridge using Lambda

  1. When the Auto Scaling group successfully launches a new admin server through a scale-out action, an “EC2 Instance Launch Successful” event is created in Amazon EventBridge.
  2. An EventBridge rule calls an AWS Lambda function, passing the event data as a JSON object.
  3. The Lambda function:
    1. parses the event data to determine the EC2 Instance ID,
    2. obtains the IP address of new server using the Instance ID, then
    3. updates the DNS A Record for the admin server in Hosted Zone we created above with the IP address.
  4. The Lambda function needs permissions to:
    • describe EC2 instances within the account (to get the IP address).
    • update the A-record in (only) the Hosted Zone we created earlier.

Working backwards, first we create the IAM Policy; second, we create the Lambda function (which references the policy); finally, we create the EventBridge rule (which references the Lambda function).

Policy

Create a policy “AllowWeblogicAdminServerUpdateDNS“ with the following JSON. Replace <MY_HOSTED_ZONE_ID> with the ID you recorded earlier.

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Effect": "Allow",
			"Action": [
				"route53:ChangeResourceRecordSets"
			],
			"Resource": "arn:aws:route53:::hostedzone/<MY_HOSTED_ZONE_ID>",
			"Condition": {
				"ForAllValues:StringLike": {
					"route53:ChangeResourceRecordSetsNormalizedRecordNames": [
						"wlsadmin.example.com"
					]
				},
				"ForAnyValue:StringEquals": {
					"route53:ChangeResourceRecordSetsRecordTypes": "A"
				}
			}
		},
		{
			"Effect": "Allow",
			"Action": [
				"ec2:DescribeInstances"
			],
			"Resource": "*"
		}
	]
}

Lambda function

We create a Lambda function named “wlsAdminARecordUpdater” with the default settings for runtime (Node.js), architecture (x86_64) and permissions.

Add an environment variable named WLSHostedZoneID and value of the Hosted Zone ID created earlier.

A role will have been created for the Lambda function with a name beginning with “wlsAdminARecordUpdater-role-“. Add the policy AllowWeblogicAdminServerUpdateDNS to this role.

Finally, add the following code then save and deploy the Lambda function.

import { EC2Client, DescribeInstancesCommand } from "@aws-sdk/client-ec2"; 
import { Route53Client, ChangeResourceRecordSetsCommand } from "@aws-sdk/client-route-53"; 
				
export const handler = async (event, context, callback) => {
  				  
  const ec2input = {
    "InstanceIds": [
      event.detail.EC2InstanceId 
    ]
  };
				
  const ec2client = new EC2Client({region: event.region});
  const route53Client = new Route53Client({region: event.region});
				  
  const ec2command = new DescribeInstancesCommand(ec2input);
  const ec2data = await ec2client.send(ec2command);
  const ec2privateip = ec2data.Reservations[0].Instances[0].PrivateIpAddress;
				    
  const r53input = {
  "ChangeBatch": {
    "Changes": [
      {
        "Action": "UPSERT",
        "ResourceRecordSet": {
          "Name": "wlsadmin.weblogic.com",
          "ResourceRecords": [
            {
              "Value": ec2privateip
            }
          ],
          "TTL": 60,
          "Type": "A"
        }
      }
    ],
    "Comment": "weblogic admin server"
    },
    "HostedZoneId": process.env.WLSHostedZoneID
  };
 const r53command = new ChangeResourceRecordSetsCommand(r53input);
 
 return await route53Client.send(r53command);
 
};

EventBridge rule

We create an EventBridge rule, “wlsAdminASG-ScaleOut”, enabled on the default event bus.

  • Rule type: “Rule with an event pattern”
  • Event Source: AWS Events or EventBridge partner events
  • Creation Method – Use pattern Form
  • Event Pattern
    • Event Source: AWS Services
    • AWS Service: Auto Scaling
    • Event Type: Instance Launch and Terminate
    • Event Type Specification 1: Specific instance event(s)
    • Event Type Specification 2: wlsadmin-asg
      The event definition should look like the following example, scoped only to the Auto Scaling group wlsadmin-asg we created earlier.

      {
        "source": ["aws.autoscaling"],
        "detail-type": ["EC2 Instance Launch Successful"],
        "detail": {
          "AutoScalingGroupName": ["wlsadmin-asg"]
        }
      }
  • Target 1: AWS Service
    • Select a target: Lambda Service
    • Function: wlsAdminARecordUpdater

Review and create the rule. Note that “EventBridge (CloudWatch Events): wlsAdminASG-ScaleOut” will be added as a trigger to the Lambda function.

If you cycle the Auto Scaling group (set min and desired to 0, let the admin server terminate, then set min and desired to 1), you will observe that after the new server is successfully launched, the value of the DNS A record wlsadmin.example.com matches the IP of the new WebLogic Admin server.

Enabling internet access to the admin server

If we want to enable internet access to the admin server, we need to create an internet-facing Application Load Balancer (ALB) attached to the public subnets. With the route to the admin server, the ALB can forward traffic to it.

  1. Create an IP-based target group that points to the wlsadmin.example.com.
  2. Add a forwarding rule in the ALB to route WebLogic admin traffic to the admin server.

Conclusion

AWS has a successful track record of running Oracle applications, Oracle EBS, PeopleSoft, and mission critical JEE workloads. In this post, we delved into leveraging DNS for the WebLogic admin server location, and using Auto Scaling groups to ensure an available and singular admin server. We showed how to automate the DNS A record update for the admin server. We also covered enabling public access to the admin server. This solution showcases multi-AZ resilience for WebLogic admin server with automated recovery.

Enhance release control with AWS CodePipeline stage-level conditions

Post Syndicated from Ryan Bachman original https://aws.amazon.com/blogs/devops/enhance-release-control-with-aws-codepipeline-stage-level-conditions/

It’s an established practice for development teams to build deployment pipelines, with services such as AWS CodePipeline, to increase the quality of application and infrastructure releases through reliable, repeatable and consistent automation.

Automating the deployment process helps build quality into our products by introducing continuous integration to build and test code, however enterprises may sometimes wish to implement certain conditions such as an approved deployment window to ensure more fine-grained control over pipeline executions.

AWS CodePipeline recently added stage-level conditions to implement pipeline gates. In this blog post, we will cover how you can implement stage-level conditions to improve your governance, code quality, and security by following a simple pipeline scenario detailed in the sections below.

AWS CodePipeline

AWS CodePipeline is a fully managed continuous delivery service that helps you automate your release pipelines for fast and reliable application and infrastructure updates.

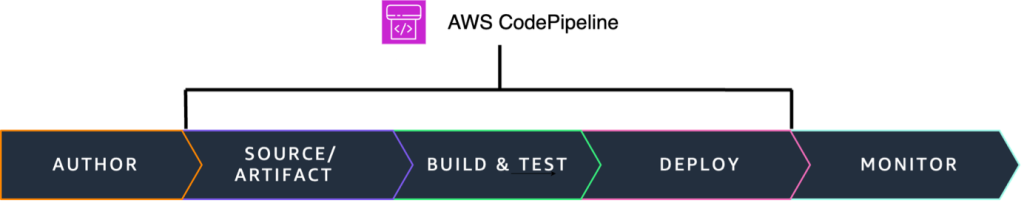
AWS CodePipeline orchestration stages

Figure 1. AWS CodePipeline orchestration

CodePipeline has three core constructs:

  • Pipelines – A pipeline is a workflow construct that describes how software changes go through a release process. Each pipeline is made up of a series of stages.
  • Stages – A stage is a logical unit you can use to isolate an environment and to limit the number of concurrent changes in that environment. Each stage contains actions that are performed on the application artifacts.
  • Actions – An action is a set of operations performed on application code and configured so that the actions run in the pipeline at a specified point.

A pipeline execution is a set of changes released by a pipeline. Each pipeline execution is unique and has its own ID. An execution corresponds to a set of changes, such as a merged commit or a manual release of the latest commit.

You can now configure stage-level conditions to gate a pipeline execution before entering the stage, as well as when exiting a stage for both success and failure state. A condition consists of one or more rules, and a result (such as rolling back) to apply when the condition fails. Conditions are also referred to as gates because they allow you to specify when an execution will enter and run through a stage or exit the stage after running through it.

You can configure a stage-level condition from the console, API, CLI, AWS CloudFormation, or SDK. For the purposes of this blog post, we will showcase how you can configure the two gate scenarios using the console. You can see how you can create conditions using the CLI in the documentation.

Scenario

For this blog, we started with a four stage Pipeline based off the Amazon ECS deployment example from this tutorial. While this tutorial provides a getting started example on how to build a CI/CD pipeline for an ECS application, it lacks the quality gates we want to enforce to ensure what we deploy to production is safe and tested. For this we will turn to CodePipeline stage-level conditions to verify certain criteria is met throughout the pipeline execution.

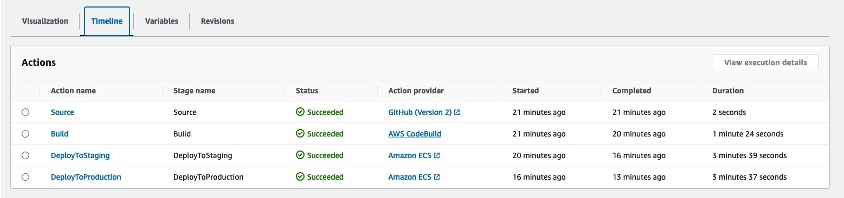
In our environment, we started with a source repository in a Github organization and used AWS CodeConnections to connect the source stage to our pipeline. Inside our repository are files for a sample application, a Dockerfile to build our application, and a buildspec.yaml file to define the steps that will be executed in the build stage of our pipeline. We added a fourth stage to our pipeline which separated production deployments after a successful deployment to the staging environment. We released a change using this pipeline to ensure everything deployed as expected.

Example of a 4-Stage CodePipeline

Figure 2: Example of a 4-Stage CodePipeline

Applying Stage Conditions

One of the primary concerns in any development process is maintaining high code quality standards. With stage-level conditions, you can now include specific checks to verify that your organization’s security and governance standards are met throughout the entire execution of your pipelines. These checks can include restricting deployments to certain days of the week, monitoring Amazon CloudWatch alarms prior to progressing, and verifying the results of security testing before promoting code as examples.

The AWS CodePipeline documentation details what conditions are available and how they can be used.

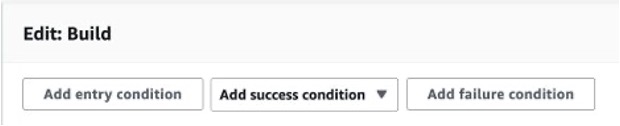
You can add conditions to stages on the pipelines detail page by choosing Edit and then selecting Edit stage from the relevant stage.

Adding a stage condition in the AWS console

Figure 3: Adding a Stage Condition in the AWS console

In our pipeline, we added rules that address three scenarios:

  • Scenario 1 – “On Success” condition that fails if the Amazon Elastic Container Registry (Amazon ECR) image scanning detects a critical severity in the Docker image in the build stage.
  • Scenario 2 – “On Failure” condition that rolls back a deployment stage in the event a CloudWatch alarm triggers after a successful deployment.
  • Scenario 3 – “Entry” condition to prevent deploying to production on Fridays, Saturdays and Sundays

Scenario 1 – “On Success” condition

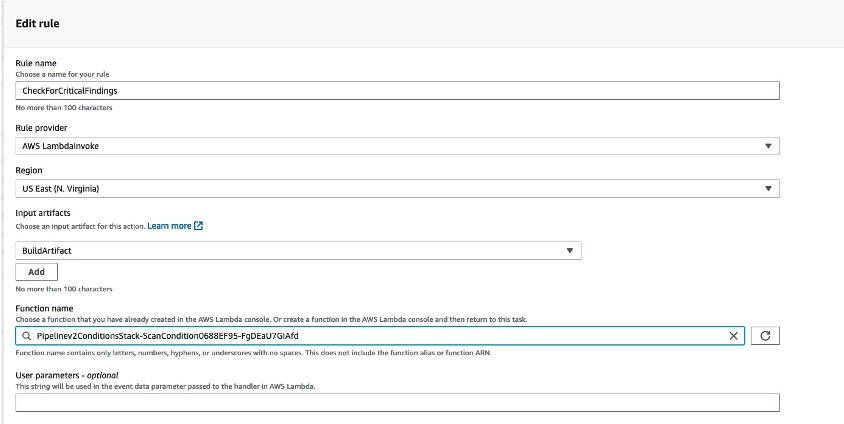
For the first gate we implemented an OnSuccess exit condition that would fail the execution using the AWS Lambda Invoke rule provider. If you would like to dive deeper into this implementation, you can take a look at Logging image scan findings from Amazon ECR in CloudWatch using an AWS Lambda function.

Lambda invoke rule in the console

Figure 4: Lambda invoke rule in the console

Before we added this condition rule, we created a Lambda function in the same region that was responsible for getting the findings from an image scan that Amazon ECR executed. If a critical finding was detected in the image, the Lambda function will fail the condition. You can read more about utilizing Lambda with CodePipeline in the documentation. The LambdaInvoke rule is able to use input artifacts to implement additional logic in the function. Here we passed in the artifact created during the build stage which contains the ECR image name and tag. This pattern allows you to re-use Lambda functions as conditions across many pipelines.

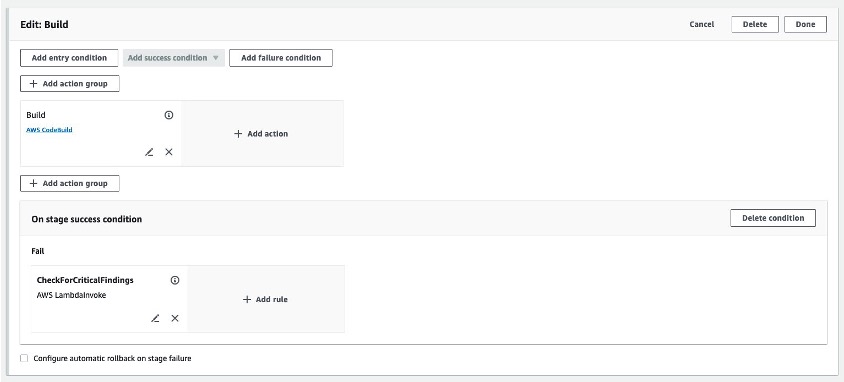
After configuring the rule, we reviewed our stage configuration and saved the pipeline.

Adding a stage condition to the build stage

Figure 5: Adding a stage condition to the build stage

Scenario 2 – “On Failure” condition

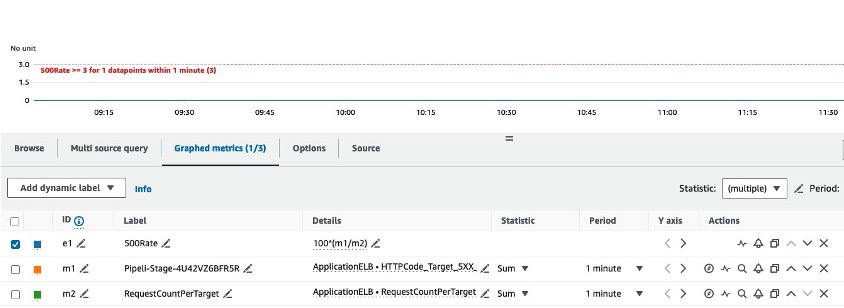
Next, we configured a condition to fail and rollback a deployment in our staging environment. If you would like to read more about implementing rollback in your CodePipeline pipelines, you can refer to De-risk releases with AWS CodePipeline rollbacks. Oftentimes a deployment will appear successful, but regressions in the code, or bugs in a new feature, may surface only when users interact with the application. To mitigate this risk, we configured a CloudWatch alarm to alert when error rates exceeded 3% of overall traffic.

CloudWatch alarm definition

Figure 6: Amazon CloudWatch alarm definition

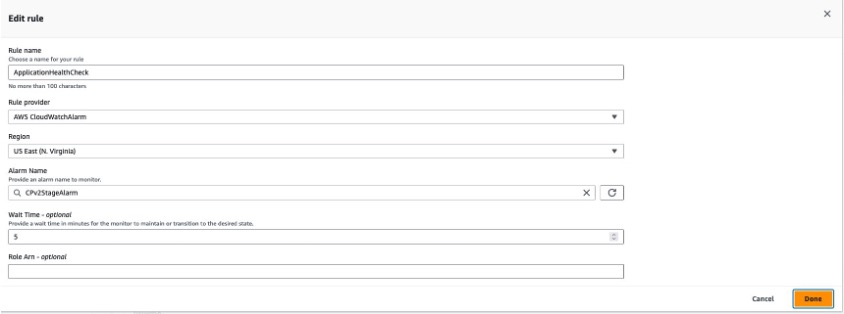
We then added an OnSuccess condition to the DeployToStage stage with a rollback rule that tracks the CloudWatch alarm configured for the above error rate metric. A wait time was configured in the rule to allow time for CloudWatch to detect any increase in errors related to the new deployment.

AWS CodePipeline condition rule using Amazon CloudWatch

Figure 7: AWS CodePipeline condition rule using Amazon CloudWatch

Scenario 3 – “Entry” condition

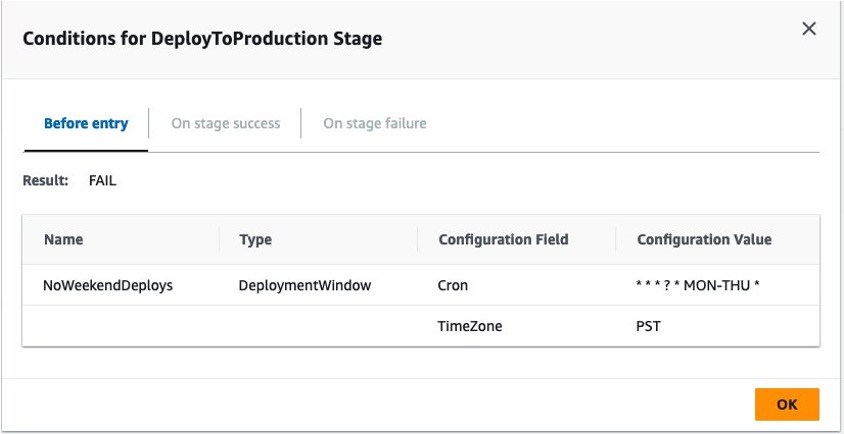
Finally, we added a third condition as an entry condition to the DeployToProduction stage. We added an AWS DeploymentWindow rule provider with a cron expression to fail the condition if a deployment to production was executed outside of our defined window.

Cron rule for AWS CodePipeline stage conditions

Figure 8: Cron rule for AWS CodePipeline stage conditions

Testing Stage Conditions

Testing Scenario 1

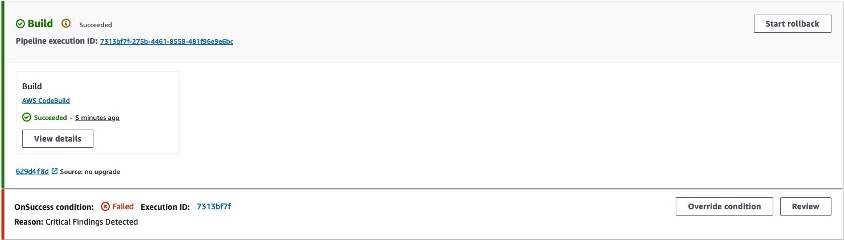
To test our CodePipeline with these stage-level conditions, we executed a git push to the source repository, which triggered a new pipeline execution. Our build stage successfully built a Docker image and pushed that image to the ECR repository, triggering the OnSuccess condition to check for critical vulnerabilities. The Lambda function reported that the scan exceeded our vulnerability threshold and stopped our pipeline with a reason of “Critical Findings Detected”

ECR scan condition failure

Figure 9: Amazon ECR scan condition failure

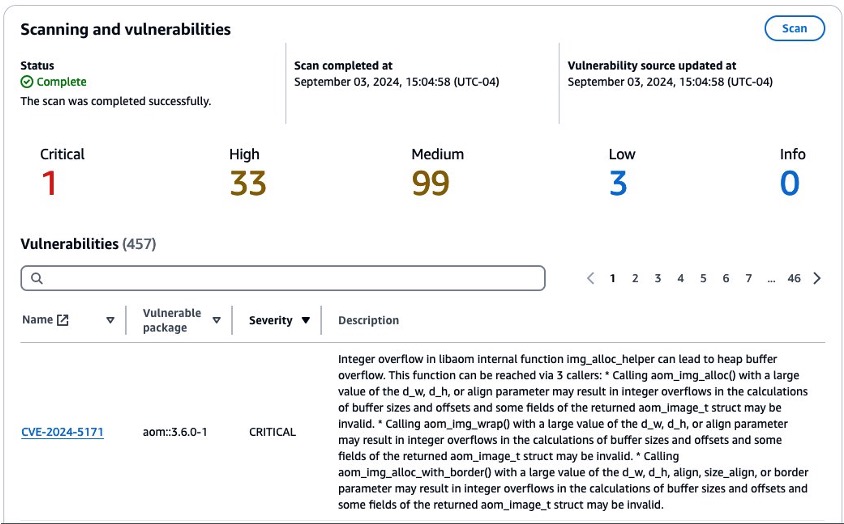
Navigating to the Amazon Elastic Container Registry service console, we were able to identify the critical vulnerability.

Amazon ECR vulnerability report

Figure 10: Amazon ECR vulnerability report

By reading the CVE we learned that the finding was related to a system package present in the source image defined in our Dockerfile. To remediate this issue, we added a new line to the Dockerfile in our source repository. The full Dockerfile is shown below for example with the change highlighted.

FROM public.ecr.aws/docker/library/python:3.12

WORKDIR /qchess
COPY . /qchess/
RUN apt-get remove --purge git git-man -y
RUN cd /qchess && pip install -r requirements.txt
RUN apt update && apt upgrade -y

CMD ["flask","run","--host=0.0.0.0","--port=80"]

With this change, we ensured that our image’s system packages would be upgraded on every build along with the version of the vulnerable package discovered by our condition check. We committed and pushed to our source repository to trigger a new pipeline execution.

Testing Scenario 2

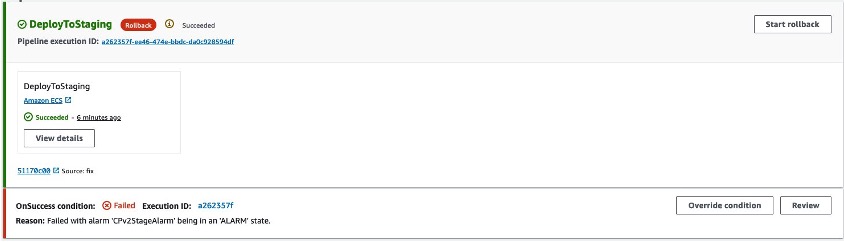
During the next run, our Pipeline made it to the DeployToStage stage and successfully deployed our code changes to our staging environment. However, when the OnSuccess condition was executed, it detected that the error rate alarm had transitioned to alarm status, resulting in the stage condition to issue a rollback. We had a bug in our new feature!

CloudWatch Rule triggering a stage rollback

Figure 11: CloudWatch Rule triggering a stage rollback

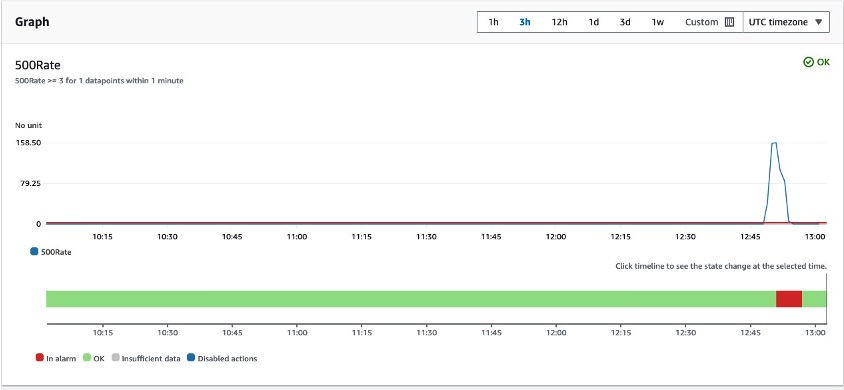
We reviewed the CloudWatch alarm and noticed the elevated error rates related to the deployment. The error rates returned to normal after the stage completed its rollback.

Amazon CloudWatch alarm details

Figure 12: Amazon CloudWatch alarm details

After this rollback we reviewed our code changes and discovered a bug in the code. We made the appropriate changes and pushed to our main branch.

Testing Scenario 3

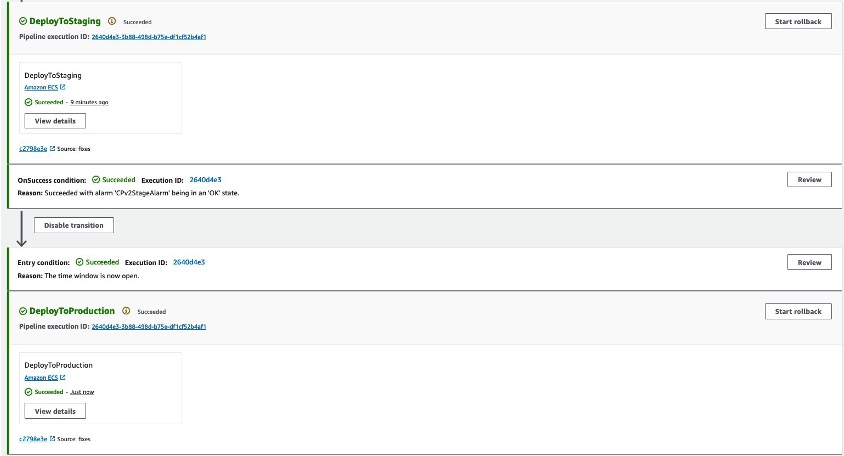
In the final pipeline execution, the pipeline made it past our DeployToStage condition and entered the entry condition in our DeployToProduction stage. This condition verified that the deployment was being executed within the defined deployment window and successfully deployed our change to production.

Deployment window allowed by condition rule

Figure 13: Deployment window allowed by stage condition rule

Clean up

If you followed along you should remove any resources you created related to this scenario. These resources include:

  • ECS Services
  • ECR Repository
  • CodeBuild Project
  • CodePipeline Pipeline
  • Lambda Function
  • CloudWatch Alarm
  • Associated IAM roles

Conclusion

Adding conditions to your AWS CodePipeline pipelines allows you to have fine-grained control over your pipeline. We have seen how you can safely automate deployments based on variables relevant to your organization. To learn more about CodePipeline conditions, visit How do stage conditions work.

Further reading

About the Authors:
Ryan Bachman profile image

Ryan Bachman

Ryan Bachman is a Sr. Specialist Solutions Architect with Amazon Web Services (AWS) with a focus on DevOps. Ryan is passionate about helping customers adopt process and services that increase their efficiency developing applications for the cloud. He has over 20 years professional experience as a technologist, including roles in development, network architecture, and technical product management.

Mirabela Dan profile image

Mirabela Dan

Mirabela Dan is a Solutions Architect for AWS with a focus on Next Generation Developer Experience and building Generative AI applications. She is passionate about DevOps and making developers lives easier with automation and productivity solutions. Outside of work, Mirabela loves travelling (70+ countries) and is a keen museum-goer and reader of history books.

More Details on Israel Sabotaging Hezbollah Pagers and Walkie-Talkies

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/more-details-on-israel-sabotaging-hezbollah-pagers-and-walkie-talkies.html

The Washington Post has a long and detailed story about the operation that’s well worth reading (alternate version here).

The sales pitch came from a marketing official trusted by Hezbollah with links to Apollo. The marketing official, a woman whose identity and nationality officials declined to reveal, was a former Middle East sales representative for the Taiwanese firm who had established her own company and acquired a license to sell a line of pagers that bore the Apollo brand. Sometime in 2023, she offered Hezbollah a deal on one of the products her firm sold: the rugged and reliable AR924.

“She was the one in touch with Hezbollah, and explained to them why the bigger pager with the larger battery was better than the original model,” said an Israeli official briefed on details of the operation. One of the main selling points about the AR924 was that it was “possible to charge with a cable. And the batteries were longer lasting,” the official said.

As it turned out, the actual production of the devices was outsourced and the marketing official had no knowledge of the operation and was unaware that the pagers were physically assembled in Israel under Mossad oversight, officials said. Mossad’s pagers, each weighing less than three ounces, included a unique feature: a battery pack that concealed a tiny amount of a powerful explosive, according to the officials familiar with the plot.

In a feat of engineering, the bomb component was so carefully hidden as to be virtually undetectable, even if the device was taken apart, the officials said. Israeli officials believe that Hezbollah did disassemble some of the pagers and may have even X-rayed them.

Also invisible was Mossad’s remote access to the devices. An electronic signal from the intelligence service could trigger the explosion of thousands of the devices at once. But, to ensure maximum damage, the blast could also be triggered by a special two-step procedure required for viewing secure messages that had been encrypted.

“You had to push two buttons to read the message,” an official said. In practice, that meant using both hands.

Also read Bunnie Huang’s essay on what it means to live in a world where people can turn IoT devices into bombs. His conclusion:

Not all things that could exist should exist, and some ideas are better left unimplemented. Technology alone has no ethics: the difference between a patch and an exploit is the method in which a technology is disclosed. Exploding batteries have probably been conceived of and tested by spy agencies around the world, but never deployed en masse because while it may achieve a tactical win, it is too easy for weaker adversaries to copy the idea and justify its re-deployment in an asymmetric and devastating retaliation.

However, now that I’ve seen it executed, I am left with the terrifying realization that not only is it feasible, it’s relatively easy for any modestly-funded entity to implement. Not just our allies can do this—a wide cast of adversaries have this capability in their reach, from nation-states to cartels and gangs, to shady copycat battery factories just looking for a big payday (if chemical suppliers can moonlight in illicit drugs, what stops battery factories from dealing in bespoke munitions?). Bottom line is: we should approach the public policy debate around this assuming that someday, we could be victims of exploding batteries, too. Turning everyday objects into fragmentation grenades should be a crime, as it blurs the line between civilian and military technologies.

I fear that if we do not universally and swiftly condemn the practice of turning everyday gadgets into bombs, we risk legitimizing a military technology that can literally bring the front line of every conflict into your pocket, purse or home.

Learn how to deploy Falcon 2 11B on Amazon EC2 c7i instances for model Inference

Post Syndicated from Anusha Jampala original https://aws.amazon.com/blogs/compute/learn-how-to-deploy-falcon-2-11b-on-amazon-ec2-c7i-instances-for-model-inference/

This post is written by Paul Tran, Senior Specialist SA; Asif Mujawar, Specialist SA Leader; Abdullatif AlRashdan, Specialist SA; and Shivagami Gugan, Enterprise Technologist.

Technology Innovation Institute (TII) has developed Falcon 2 11B foundation model (FM), a next-generation AI model that can be now deployed on Amazon Elastic Compute Cloud (Amazon EC2) c7i instances, which support Intel Advanced Matrix Extensions (Intel AMX). Intel AMX is designed to accelerate matrix operations on a CPU, which is fundamental for deep learning and AI workloads.

This post walks through the concept of model quantization and why quantization is vital for real-time use cases. You will be able to reproduce this process and run the model on a CPU at the end of this post.

Open source developers and customers can now use the EC2 C7i instance family to run their AI-powered applications using the Falcon 2 11B model on a CPU, offering a cost-effective alternative to the traditional GPU route to build cost-efficient solutions. It also unlocks deployment of the large language model (LLM) on widely available hardware that enables deployment of efficient and scalable AI applications.

Falcon 2 11B model

Falcon 2 11B is the first FM model from TII’s newly released Falcon 2 series. It is a more efficient and accessible LLM that was trained on a massive dataset of 5.5 trillion tokens consisting of web data from RefinedWeb. The model is built on causal decoder-only architecture with 11 billion trainable parameters, making it powerful for autoregressive tasks. It’s equipped with multilingual capabilities and can seamlessly tackle tasks in English, French, Spanish, German, Portuguese, and other languages for diverse scenarios. The new Falcon 2 Series, trained on Amazon SageMaker, widens the capabilities of Falcon by making it more efficient and multilingual. More detailed information on the previous generation of Falcon models can be found at RefinedWeb, Falcon 40B foundation model from TII available on SageMaker JumpStart, and Falcon 180B foundation model from TII is now available via Amazon SageMaker JumpStart.

Falcon 2 11B is supported by the Amazon SageMaker Text Generation Inference (TGI) Deep Learning Container (DLC), an open source, purpose-built solution for deploying and serving LLMs that enables high performance text generation using tensor parallelism and dynamic batching. The model is available under the TII Falcon License 2.0, the permissive Apache 2.0-based software license, which includes an acceptable use policy that promotes the responsible use of AI. In addition, Falcon 2 11B is now available on Amazon SageMaker JumpStart.

INT8 and INT4 quantization

For real-time applications such as Retrieval Augmented Generation (RAG) or code generation, reducing the latency for generating the first token is crucial, and minimizing the time between generating subsequent tokens promotes a seamless experience. These benefits are essential for applications that require real-time interaction, where even minor delays could disrupt the user experience and hinder productivity.

The OpenVINO framework enables INT8 and INT4 quantization and weight compression. This optimizes performance by reducing the model size and computational demands, making generative AI more cost-effective. These optimizations lower inference cost while maintaining high quality outputs.

Intel AMX is a new built-in accelerator that improves the performance of deep learning training and inference on the CPU. It provides significant performance advantages for INT8 and INT4 inferencing by accelerating matrix multiplication for deep learning workloads, which are essential in AI model execution. By using AMX, INT8 and INT4 precision models can run faster and more efficiently, without substantial loss in accuracy, providing for quicker inference and lower power consumption.

Benchmark results summary

The C7i.24xlarge instance was used for benchmarking the inference performance of the Falcon 2 11B model. The results showcased the effectiveness of INT8 and INT4 quantization techniques, using the OpenVINO toolkit. The results demonstrate significant improvements in latency and throughput.

The code to reproduce the benchmarks on the c7i instance can be found at openvino.genai. Please note that benchmarking performance varies by use, configuration, and other factors.

Case 1

Quantization technique using INT8 Falcon 2 11B with OpenVINO on c7i.24xlarge.

Quantization Batch

Input

prompt tokens

Output tokens

First token

latency ms/token

Second token latency ms/token Throughput tokens/s
INT8 1 32 128 148.07 82.51 12.12
INT8 1 64 128 189.98 79.74 12.54
INT8 1 128 128 283.50 80.26 12.46
INT8 1 512 128 1037.25 82.03 12.19
INT8 1 1024 128 1961.91 84.76 11.80
INT8 1 2048 128 4068.90 90.40 11.06

Table 1: Quantization technique using INT8 Falcon 2 11B with OpenVINO on c7i.24xlarge

Case 2

Quantization technique using INT4 Falcon11B with OpenVINO on c7i.24xlarge.

Quantization Batch

Input

prompt tokens

Output

tokens

First token latency ms/token Second token latency ms/token Throughput tokens/s
INT4 1 32 128 142.00 59.06 16.93
INT4 1 64 128 195.73 82.58 12.11
INT4 1 128 128 274.67 80.40 12.44
INT4 1 512 128 991.34 82.22 12.16
INT4 1 1024 128 1922.87 85.18 11.74
INT4 1 2048 128 4079.58 90.11 11.10

As these results show, INT8 quantization provides excellent latency and throughput numbers. This demonstrates how suitable inference on a CPU is for real-time use cases such as RAG or code generation. Increased performance can also be obtained with more aggressive quantization, such as INT4.

AWS customers can now explore and deploy Falcon 2 11B models using c7i instances across AWS Regions with dedicated performance improvements using OpenVINO Toolkit.

Quantize Falcon 2 11B using OpenVINO and run inference

Developers can use the following approach to quantize Falcon 2 11B and optimize to run on CPU instances. The model is pulled from HuggingFace hub through the OpenVINO framework. A full list of compatible models can be found at AI Models verified for OpenVINO.

For the model quantization, the process requires large RAM memory peaking up to over 116 GB for 11 billion parameters at full precision, hence the choice of running the experiments on c7i.24xlarge equipped with 192 GB of RAM for convenience.

This is shown in the following figure during quantization.

Figure 1: Model quantization

Once quantization is achieved, the converted model weights are stored in the instance disk ready to be consumed for inference.

The inference memory requirement is lower compared to the quantization process because the memory footprint of the quantized model for inference is approximately 12 GB, as illustrated in following figure. Running the inference on the c7i.24xlarge instance allows you to benefit from the increased number of cores, which directly correlates with model speed.

Figure 2: Memory footprint of quantized model for inference

Quantize Falcon 2 11B

To quantize Falcon 2 11B using OpenVINO, complete the following steps:

1. Create c7i.24xlarge EC2 instance in your AWS account.
2. Size the Amazon Elastic Block Store (Amazon EBS) storage depending on the number of models you need to experiment with. For instance, using Falcon 2 11B model weights at full precision requires approximately 24 GB of storage. For comfort, we recommend running with at least 150 GB of storage to experiment with different precisions and models.
3. Connect to your EC2 instance. See Connect to your EC2 instance to see the different options you can use to access your EC2 instance.
4. Create a virtual environment using the following code example.

python3 -m venv ov-llm-bench-env
source ov-llm-bench-env/bin/activate
pip install --upgrade pipClone the repository and navigate to the source directory.

5. Clone repository and navigate to the source directory:

git clone https://github.com/openvinotoolkit/openvino.genai.git
cd openvino.genai/llm_bench/python/

6. Install dependencies:

pip install -r requirements.txt

7. Run model conversion:

python convert.py --model_id tiiuae/falcon-11B --output_dir model_weights/int8/ --compress_weights INT8 4BIT_DEFAULT

This command perform quantization using OpenVINO on Falcon2-11B model. It downloads the model from HuggingFace and output the converted model in the path specified in -output_dir

Test Falcon2-11B for inference

OpenVINO provides a convenient interface that allows to use the model with HuggingFace transformers library. Run the following python script on your EC2 instance to test inference:

from transformers import AutoTokenizer
from optimum.intel.openvino import OVModelForCausalLM
 
if __name__ == '__main__':
    model_path= "model_weights/int8/pytorch/dldt/compressed_weights/OV_FP32-INT8/"
    tokenizer = AutoTokenizer.from_pretrained(model_path)
    model = OVModelForCausalLM.from_pretrained(model_path)
 
    inputs = tokenizer("What is OpenVINO?", return_tensors="pt")
 
    outputs = model.generate(**inputs, max_length=200)
    text = tokenizer.batch_decode(outputs)[0]
    print(text)# Falcon2-11B inference completion

The following screenshot shows a sample generated from the previous code. The output is truncated to generate 200 tokens maximum.

Figure 3: Inference results after running Python script

Conclusion

In this post, we showcased Falcon 2 11B quantization and optimized performance using OpenVINO on AMX capable EC2 c7i instances. This enables deployment of LLM-based applications on widely available CPUs with high performance as a cost-effective alternative without sacrificing speed. These optimizations significantly lower inference costs while maintaining high-quality outputs.

For more information, refer to Amazon EC2 C7i and C7i-flex instances, SageMaker JumpStart pre-trained models, Amazon SageMaker JumpStart Foundation Models, OpenVINO, and the reference code for quantization.

Leave your feedback in the comments so we can continue to improve upon this benchmark.

Perfectl Malware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/perfectl-malware.html

Perfectl in an impressive piece of malware:

The malware has been circulating since at least 2021. It gets installed by exploiting more than 20,000 common misconfigurations, a capability that may make millions of machines connected to the Internet potential targets, researchers from Aqua Security said. It can also exploit CVE-2023-33246, a vulnerability with a severity rating of 10 out of 10 that was patched last year in Apache RocketMQ, a messaging and streaming platform that’s found on many Linux machines.

The researchers are calling the malware Perfctl, the name of a malicious component that surreptitiously mines cryptocurrency. The unknown developers of the malware gave the process a name that combines the perf Linux monitoring tool and ctl, an abbreviation commonly used with command line tools. A signature characteristic of Perfctl is its use of process and file names that are identical or similar to those commonly found in Linux environments. The naming convention is one of the many ways the malware attempts to escape notice of infected users.

Perfctl further cloaks itself using a host of other tricks. One is that it installs many of its components as rootkits, a special class of malware that hides its presence from the operating system and administrative tools. Other stealth mechanisms include:

  • Stopping activities that are easy to detect when a new user logs in
  • Using a Unix socket over TOR for external communications
  • Deleting its installation binary after execution and running as a background service thereafter
  • Manipulating the Linux process pcap_loop through a technique known as hooking to prevent admin tools from recording the malicious traffic
  • Suppressing mesg errors to avoid any visible warnings during execution.

The malware is designed to ensure persistence, meaning the ability to remain on the infected machine after reboots or attempts to delete core components. Two such techniques are (1) modifying the ~/.profile script, which sets up the environment during user login so the malware loads ahead of legitimate workloads expected to run on the server and (2) copying itself from memory to multiple disk locations. The hooking of pcap_loop can also provide persistence by allowing malicious activities to continue even after primary payloads are detected and removed.

Besides using the machine resources to mine cryptocurrency, Perfctl also turns the machine into a profit-making proxy that paying customers use to relay their Internet traffic. Aqua Security researchers have also observed the malware serving as a backdoor to install other families of malware.

Something this complex and impressive implies that a government is behind this. North Korea is the government we know that hacks cryptocurrency in order to fund its operations. But this feels too complex for that. I have no idea how to attribute this.