Tag Archives: Uncategorized

Buying Campaign Contributions as a Hack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/buying-campaign-contributions-as-a-hack.html

The first Republican primary debate has a popularity threshold to determine who gets to appear: 40,000 individual contributors. Now there are a lot of conventional ways a candidate can get that many contributors. Doug Burgum came up with a novel idea: buy them:

A long-shot contender at the bottom of recent polls, Mr. Burgum is offering $20 gift cards to the first 50,000 people who donate at least $1 to his campaign. And one lucky donor, as his campaign advertised on Facebook, will have the chance to win a Yeti Tundra 45 cooler that typically costs more than $300—just for donating at least $1.

It’s actually a pretty good idea. He could have spent the money on direct mail, or personalized social media ads, or television ads. Instead, he buys gift cards at maybe two-thirds of face value (sellers calculate the advertising value, the additional revenue that comes from using them to buy something more expensive, and breakage when they’re not redeemed at all), and resells them. Plus, many contributors probably give him more than $1, and he got a lot of publicity over this.

Probably the cheapest way to get the contributors he needs. A clever hack.

EDITED TO ADD (7/16): These might be “straw donors” and illegal:

The campaign’s donations-for-cash strategy could raise potential legal concerns, said Paul Ryan, a campaign finance lawyer. Voters who make donations in exchange for gift cards, he said, might be considered straw donors because part or all of their donations are being reimbursed by the campaign.

“Federal law says ‘no person shall make a contribution in the name of another person,’” Mr. Ryan said. “Here, the candidate is making a contribution to himself in the name of all these individual donors.”

Richard L. Hasen, a law professor at the University of California, Los Angeles, who specializes in election law, said that typically, campaigns ask the Federal Election Commission when engaging in new forms of donations.

The Burgum campaign’s maneuver, he said, “certainly seems novel” and “raises concerns about whether it violates the prohibition on straw donations.”

Something for the courts to figure out, if this matter ever gets that far.

Directing ML-powered Operational Insights from Amazon DevOps Guru to your Datadog event stream

Post Syndicated from Bineesh Ravindran original https://aws.amazon.com/blogs/devops/directing_ml-powered_operational_insights_from_amazon_devops_guru_to_your_datadog_event_stream/

Amazon DevOps Guru is a fully managed AIOps service that uses machine learning (ML) to quickly identify when applications are behaving outside of their normal operating patterns and generates insights from its findings. These insights generated by DevOps Guru can be used to alert on-call teams to react to anomalies for business mission critical workloads. If you are already utilizing Datadog to automate infrastructure monitoring, application performance monitoring, and log management for real-time observability of your entire technology stack, then this blog is for you.

You might already be using Datadog for a consolidated view of your Datadog Events interface to search, analyze and filter events from many different sources in one place. Datadog Events are records of notable changes relevant for managing and troubleshooting IT Operations, such as code, deployments, service health, configuration changes and monitoring alerts.

Wherever DevOps Guru detects operational events in your AWS environment that could lead to outages, it generates insights and recommendations. These insights/recommendations are then pushed to a user specific Datadog endpoint using Datadog events API. Customers can then create dashboards, incidents, alarms or take corrective automated actions based on these insights and recommendations in Datadog.

Datadog collects and unifies all of the data streaming from these complex environments, with a 1-click integration for pulling in metrics and tags from over 90 AWS services. Companies can deploy the Datadog Agent directly on their hosts and compute instances to collect metrics with greater granularity—down to one-second resolution. And with Datadog’s out-of-the-box integration dashboards, companies get not only a high-level view into the health of their infrastructure and applications but also deeper visibility into individual services such as AWS Lambda and Amazon EKS.

This blogpost will show you how to utilize Amazon DevOps guru with Datadog to get real time insights and recommendations on their AWS Infrastructure. We will demonstrate how an insight generated by Amazon DevOps Guru for an anomaly can automatically be pushed to Datadog’s event streams which can then be used to create dashboards, create alarms and alerts to take corrective actions.

Solution Overview

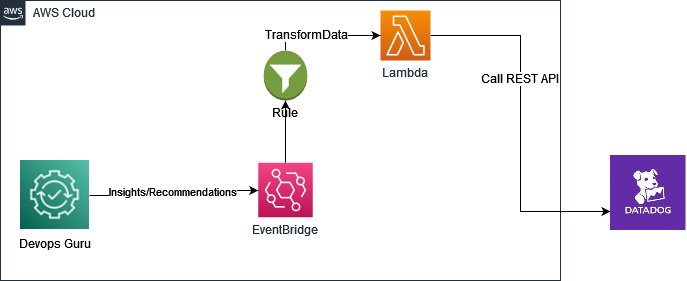
When an Amazon DevOps Guru insight is created, an Amazon EventBridge rule is used to capture the insight as an event and routed to an AWS Lambda Function target. The lambda function interacts with Datadog using a REST API to push corresponding DevOps Guru events captured by Amazon EventBridge

The EventBridge rule can be customized to capture all DevOps Guru insights or narrowed down to specific insights. In this blog, we will be capturing all DevOps Guru insights and will be performing actions on Datadog for the below DevOps Guru events:

  • DevOps Guru New Insight Open
  • DevOps Guru New Anomaly Association
  • DevOps Guru Insight Severity Upgraded
  • DevOps Guru New Recommendation Created
  • DevOps Guru Insight Closed
Figure 1: Amazon DevOps Guru Integration with Datadog with Amazon EventBridge and AWS.

Figure 1: Amazon DevOps Guru Integration with Datadog with Amazon EventBridge and AWS.

Solution Implementation Steps

Pre-requisites

Before you deploy the solution, complete the following steps.

    • Datadog Account Setup: We will be connecting your AWS Account with Datadog. If you do not have a Datadog account, you can request a free trial developer instance through Datadog.
    • Datadog Credentials: Gather the credentials of Datadog keys that will be used to connect with AWS. Follow the steps below to create an API Key and Application Key
      Add an API key or client token

        1. To add a Datadog API key or client token:
        2. Navigate to Organization settings, then click the API keys or Client Tokens
        3. Click the New Key or New Client Token button, depending on which you’re creating.
        4. Enter a name for your key or token.
        5. Click Create API key or Create Client Token.
        6. Note down the newly generated API Key value. We will need this in later steps
        7. Figure 2: Create new API Key.

          Figure 2: Create new API Key.

      Add application keys

      • To add a Datadog application key, navigate to Organization Settings > Application Keys.If you have the permission to create application keys, click New Key.Note down the newly generated Application Key. We will need this in later steps

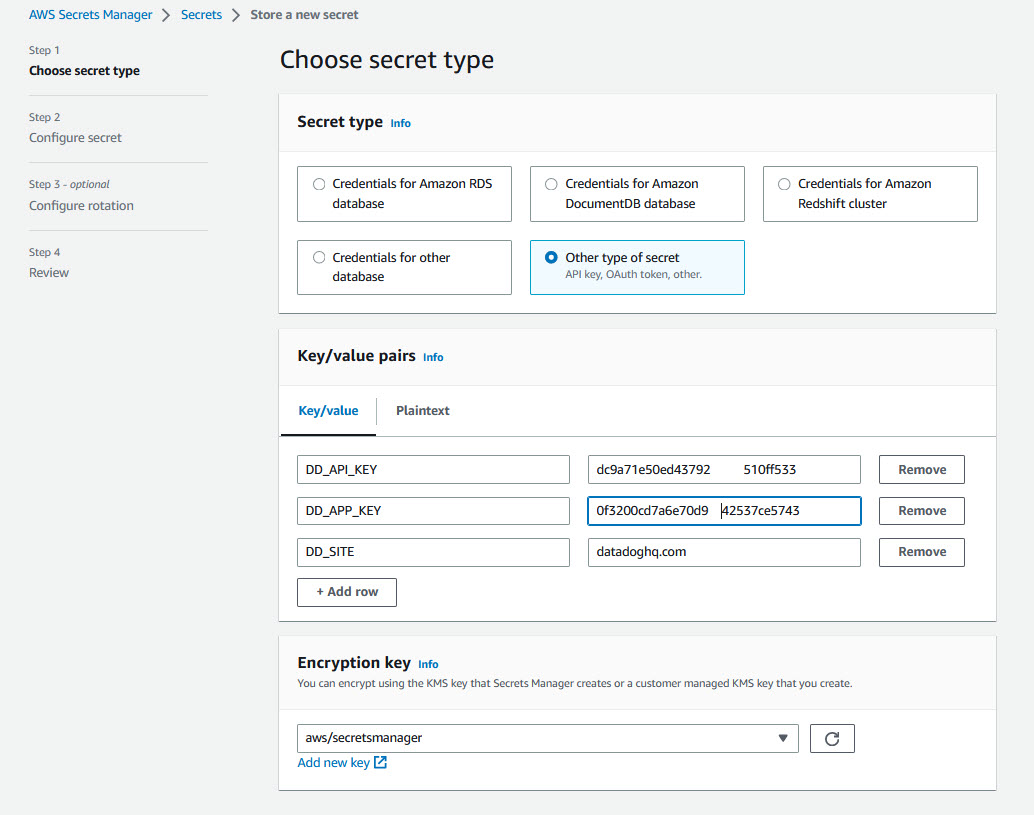
Add Application Key and API Key to AWS Secrets Manager : Secrets Manager enables you to replace hardcoded credentials in your code, including passwords, with an API call to Secrets Manager to retrieve the secret programmatically. This helps ensure the secret can’t be compromised by someone examining your code,because the secret no longer exists in the code.
Follow below steps to create a new secret in AWS Secrets Manager.

  1. Open the Secrets Manager console at https://console.aws.amazon.com/secretsmanager/
  2. Choose Store a new secret.
  3. On the Choose secret type page, do the following:
    1. For Secret type, choose other type of secret.
    2. In Key/value pairs, either enter your secret in Key/value
      pairs
Figure 3: Create new secret in Secret Manager.

Figure 3: Create new secret in Secret Manager.

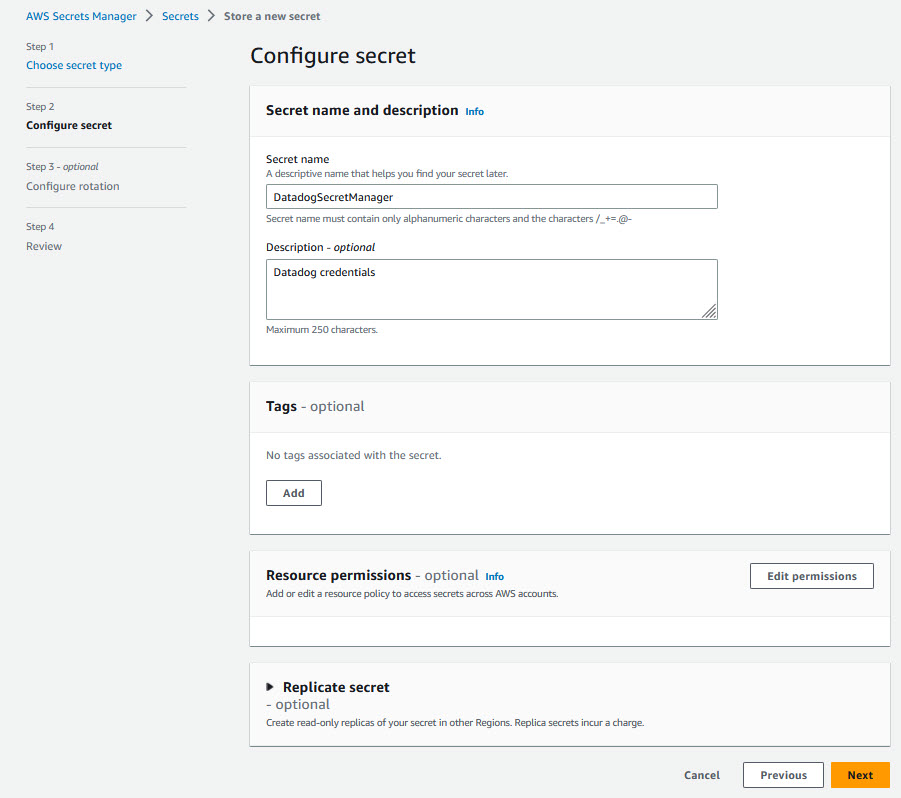
Click next and enter “DatadogSecretManager” as the secret name followed by Review and Finish

Figure 4: Configure secret in Secret Manager.

Figure 4: Configure secret in Secret Manager.

Option 1: Deploy Datadog Connector App from AWS Serverless Repository

The DevOps Guru Datadog Connector application is available on the AWS Serverless Application Repository which is a managed repository for serverless applications. The application is packaged with an AWS Serverless Application Model (SAM) template, definition of the AWS resources used and the link to the source code. Follow the steps below to quickly deploy this serverless application in your AWS account

      • Login to the AWS management console of the account to which you plan to deploy this solution.
      • Go to the DevOps Guru Datadog Connector application in the AWS Serverless Repository and click on “Deploy”.
      • The Lambda application deployment screen will be displayed where you can enter the Datadog Application name
        Figure 5: DevOps Guru Datadog connector.

        Figure 5: DevOps Guru Datadog connector.

         Figure 6: Serverless Application DevOps Guru Datadog connector.

        Figure 6: Serverless Application DevOps Guru Datadog connector.

      • After successful deployment the AWS Lambda Application page will display the “Create complete” status for the serverlessrepo-DevOps-Guru-Datadog-Connector application. The CloudFormation template creates four resources,
        1. Lambda function which has the logic to integrate to the Datadog
        2. Event Bridge rule for the DevOps Guru Insights
        3. Lambda permission
        4. IAM role
      • Now skip Option 2 and follow the steps in the “Test the Solution” section to trigger some DevOps Guru insights/recommendations and validate that the events are created and updated in Datadog.

Option 2: Build and Deploy sample Datadog Connector App using AWS SAM Command Line Interface

As you have seen above, you can directly deploy the sample serverless application form the Serverless Repository with one click deployment. Alternatively, you can choose to clone the GitHub source repository and deploy using the SAM CLI from your terminal.

The Serverless Application Model Command Line Interface (SAM CLI) is an extension of the AWS CLI that adds functionality for building and testing serverless applications. The CLI provides commands that enable you to verify that AWS SAM template files are written according to the specification, invoke Lambda functions locally, step-through debug Lambda functions, package and deploy serverless applications to the AWS Cloud, and so on. For details about how to use the AWS SAM CLI, including the full AWS SAM CLI Command Reference, see AWS SAM reference – AWS Serverless Application Model.

Before you proceed, make sure you have completed the pre-requisites section in the beginning which should set up the AWS SAM CLI, Maven and Java on your local terminal. You also need to install and set up Docker to run your functions in an Amazon Linux environment that matches Lambda.

Clone the source code from the github repo

git clone https://github.com/aws-samples/amazon-devops-guru-connector-datadog.git

Build the sample application using SAM CLI

$cd DatadogFunctions

$sam build
Building codeuri: $\amazon-devops-guru-connector-datadog\DatadogFunctions\Functions runtime: java11 metadata: {} architecture: x86_64 functions: Functions
Running JavaMavenWorkflow:CopySource
Running JavaMavenWorkflow:MavenBuild
Running JavaMavenWorkflow:MavenCopyDependency
Running JavaMavenWorkflow:MavenCopyArtifacts

Build Succeeded

Built Artifacts  : .aws-sam\build
Built Template   : .aws-sam\build\template.yaml

Commands you can use next
=========================
[*] Validate SAM template: sam validate
[*] Invoke Function: sam local invoke
[*] Test Function in the Cloud: sam sync --stack-name {{stack-name}} --watch
[*] Deploy: sam deploy --guided

This command will build the source of your application by installing dependencies defined in Functions/pom.xml, create a deployment package and saves it in the. aws-sam/build folder.

Deploy the sample application using SAM CLI

$sam deploy --guided

This command will package and deploy your application to AWS, with a series of prompts that you should respond to as shown below:

      • Stack Name: The name of the stack to deploy to CloudFormation. This should be unique to your account and region, and a good starting point would be something matching your project name.
      • AWS Region: The AWS region you want to deploy your application to.
      • Confirm changes before deploy: If set to yes, any change sets will be shown to you before execution for manual review. If set to no, the AWS SAM CLI will automatically deploy application changes.
      • Allow SAM CLI IAM role creation:Many AWS SAM templates, including this example, create AWS IAM roles required for the AWS Lambda function(s) included to access AWS services. By default, these are scoped down to minimum required permissions. To deploy an AWS CloudFormation stack which creates or modifies IAM roles, the CAPABILITY_IAM value for capabilities must be provided. If permission isn’t provided through this prompt, to deploy this example you must explicitly pass --capabilities CAPABILITY_IAM to the sam deploy command.
      • Disable rollback [y/N]: If set to Y, preserves the state of previously provisioned resources when an operation fails.
      • Save arguments to configuration file (samconfig.toml): If set to yes, your choices will be saved to a configuration file inside the project, so that in the future you can just re-run sam deploy without parameters to deploy changes to your application.

After you enter your parameters, you should see something like this if you have provided Y to view and confirm ChangeSets. Proceed here by providing ‘Y’ for deploying the resources.

Initiating deployment
=====================

        Uploading to sam-app-datadog/0c2b93e71210af97a8c57710d0463c8b.template  1797 / 1797  (100.00%)


Waiting for changeset to be created..

CloudFormation stack changeset
---------------------------------------------------------------------------------------------------------------------
Operation                     LogicalResourceId             ResourceType                  Replacement
---------------------------------------------------------------------------------------------------------------------
+ Add                         FunctionsDevOpsGuruPermissi   AWS::Lambda::Permission       N/A
                              on
+ Add                         FunctionsDevOpsGuru           AWS::Events::Rule             N/A
+ Add                         FunctionsRole                 AWS::IAM::Role                N/A
+ Add                         Functions                     AWS::Lambda::Function         N/A
---------------------------------------------------------------------------------------------------------------------


Changeset created successfully. arn:aws:cloudformation:us-east-1:867001007349:changeSet/samcli-deploy1680640852/bdc3039b-cdb7-4d7a-a3a0-ed9372f3cf9a


Previewing CloudFormation changeset before deployment
======================================================
Deploy this changeset? [y/N]: y

2023-04-04 15:41:06 - Waiting for stack create/update to complete

CloudFormation events from stack operations (refresh every 5.0 seconds)
---------------------------------------------------------------------------------------------------------------------
ResourceStatus                ResourceType                  LogicalResourceId             ResourceStatusReason
---------------------------------------------------------------------------------------------------------------------
CREATE_IN_PROGRESS            AWS::IAM::Role                FunctionsRole                 -
CREATE_IN_PROGRESS            AWS::IAM::Role                FunctionsRole                 Resource creation Initiated
CREATE_COMPLETE               AWS::IAM::Role                FunctionsRole                 -
CREATE_IN_PROGRESS            AWS::Lambda::Function         Functions                     -
CREATE_IN_PROGRESS            AWS::Lambda::Function         Functions                     Resource creation Initiated
CREATE_COMPLETE               AWS::Lambda::Function         Functions                     -
CREATE_IN_PROGRESS            AWS::Events::Rule             FunctionsDevOpsGuru           -
CREATE_IN_PROGRESS            AWS::Events::Rule             FunctionsDevOpsGuru           Resource creation Initiated
CREATE_COMPLETE               AWS::Events::Rule             FunctionsDevOpsGuru           -
CREATE_IN_PROGRESS            AWS::Lambda::Permission       FunctionsDevOpsGuruPermissi   -
                                                            on
CREATE_IN_PROGRESS            AWS::Lambda::Permission       FunctionsDevOpsGuruPermissi   Resource creation Initiated
                                                            on
CREATE_COMPLETE               AWS::Lambda::Permission       FunctionsDevOpsGuruPermissi   -
                                                            on
CREATE_COMPLETE               AWS::CloudFormation::Stack    sam-app-datadog               -
---------------------------------------------------------------------------------------------------------------------


Successfully created/updated stack - sam-app-datadog in us-east-1

Once the deployment succeeds, you should be able to see the successful creation of your resources. Also, you can find your Lambda, IAM Role and EventBridge Rule in the CloudFormation stack output values.

You can also choose to test and debug your function locally with sample events using the SAM CLI local functionality.Test a single function by invoking it directly with a test event. An event is a JSON document that represents the input that the function receives from the event source. Refer the Invoking Lambda functions locally – AWS Serverless Application Model link here for more details.

$ sam local invoke Functions -e ‘event/event.json’

Once you are done with the above steps, move on to “Test the Solution” section below to trigger some DevOps Guru insights and validate that the events are created and pushed to Datadog.

Test the Solution

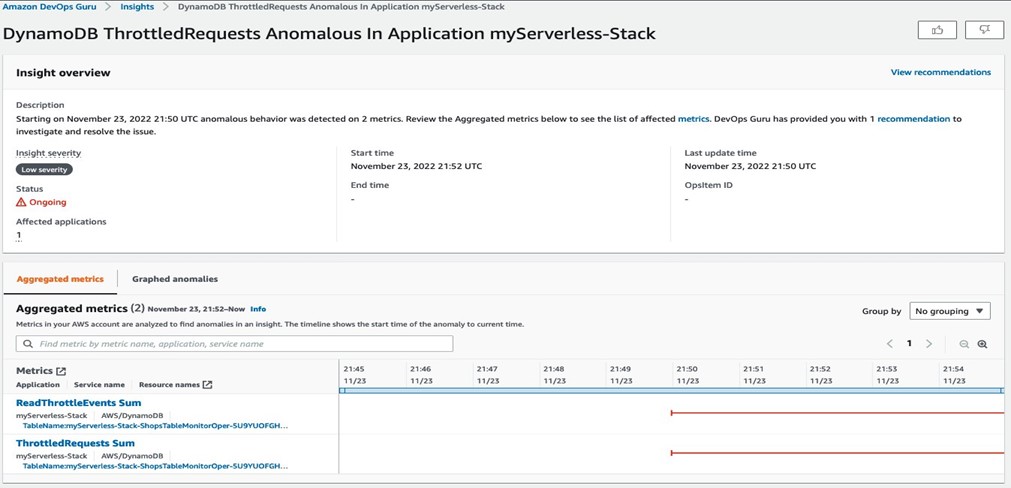
To test the solution, we will simulate a DevOps Guru Insight. You can also simulate an insight by following the steps in this blog. After an anomaly is detected in the application, DevOps Guru creates an insight as shown below

 Figure 7: DevOps Guru insight for DynamoDB

Figure 7: DevOps Guru insight for DynamoDB

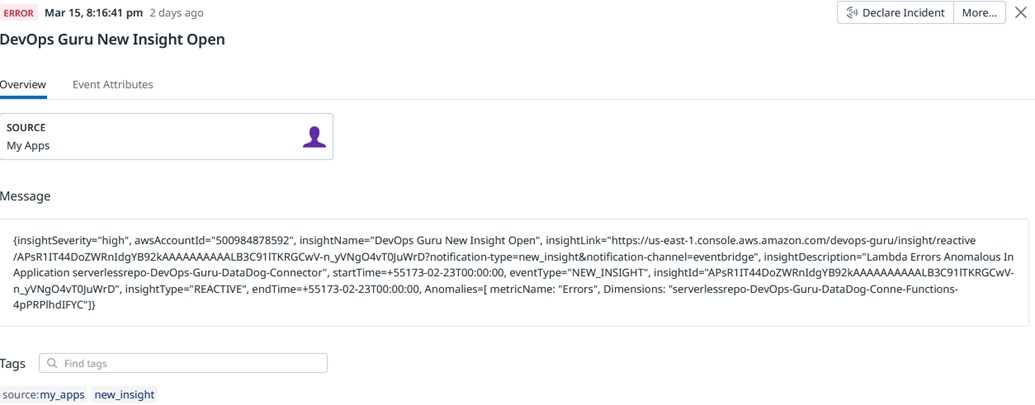
For the DevOps Guru insight shown above, a corresponding event is automatically created and pushed to Datadog as shown below. In addition to the events creation, any new anomalies and recommendations from DevOps Guru is also associated with the events

Figure 8 : DevOps Guru Insight pushed to Datadog event stream.

Figure 8 : DevOps Guru Insight pushed to Datadog event stream.

Cleaning Up

To delete the sample application that you created, In your Cloud 9 environment open a new terminal. Now type in the AWS CLI command below and pass the stack name you provided in the deploy step

aws cloudformation delete-stack --stack-name <Stack Name>

Alternatively ,you could also use the AWS CloudFormation Console to delete the stack

Conclusion

This article highlights how Amazon DevOps Guru monitors resources within a specific region of your AWS account, automatically detecting operational issues, predicting potential resource exhaustion, identifying probable causes, and recommending remediation actions. It describes a bespoke solution enabling integration of DevOps Guru insights with Datadog, enhancing management and oversight of AWS services. This solution aids customers using Datadog to bolster operational efficiencies, delivering customized insights, real-time alerts, and management capabilities directly from DevOps Guru, offering a unified interface to swiftly restore services and systems.

To start gaining operational insights on your AWS Infrastructure with Datadog head over to Amazon DevOps Guru documentation page.

About the authors:

Bineesh Ravindran

Bineesh Ravindran

Bineesh is Solutions Architect at Amazon Webservices (AWS) who is passionate about technology and love to help customers solve problems. Bineesh has over 20 years of experience in designing and implementing enterprise applications. He works with AWS partners and customers to provide them with architectural guidance for building scalable architecture and execute strategies to drive adoption of AWS services. When he’s not working, he enjoys biking, aquascaping and playing badminton..

David Ernst

David is a Sr. Specialist Solution Architect – DevOps, with 20+ years of experience in designing and implementing software solutions for various industries. David is an automation enthusiast and works with AWS customers to design, deploy, and manage their AWS workloads/architectures.

French Police Will Be Able to Spy on People through Their Cell Phones

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/french-police-will-be-able-to-spy-on-people-through-their-cell-phones.html

The French police are getting new surveillance powers:

French police should be able to spy on suspects by remotely activating the camera, microphone and GPS of their phones and other devices, lawmakers agreed late on Wednesday, July 5.

[…]

Covering laptops, cars and other connected objects as well as phones, the measure would allow the geolocation of suspects in crimes punishable by at least five years’ jail. Devices could also be remotely activated to record sound and images of people suspected of terror offenses, as well as delinquency and organized crime.

[…]

During a debate on Wednesday, MPs in President Emmanuel Macron’s camp inserted an amendment limiting the use of remote spying to “when justified by the nature and seriousness of the crime” and “for a strictly proportional duration.” Any use of the provision must be approved by a judge, while the total duration of the surveillance cannot exceed six months. And sensitive professions including doctors, journalists, lawyers, judges and MPs would not be legitimate targets.

Google Is Using Its Vast Data Stores to Train AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/google-is-using-its-vast-data-stores-to-train-ai.html

No surprise, but Google just changed its privacy policy to reflect broader uses of all the surveillance data it has captured over the years:

Research and development: Google uses information to improve our services and to develop new products, features and technologies that benefit our users and the public. For example, we use publicly available information to help train Google’s AI models and build products and features like Google Translate, Bard, and Cloud AI capabilities.

(I quote the privacy policy as of today. The Mastodon link quotes the privacy policy from ten days ago. So things are changing fast.)

Privacy of Printing Services

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/privacy-of-printing-services.html

The Washington Post has an article about popular printing services, and whether or not they read your documents and mine the data when you use them for printing:

Ideally, printing services should avoid storing the content of your files, or at least delete daily. Print services should also communicate clearly upfront what information they’re collecting and why. Some services, like the New York Public Library and PrintWithMe, do both.

Others dodged our questions about what data they collect, how long they store it and whom they share it with. Some—including Canon, FedEx and Staples—declined to answer basic questions about their privacy practices.

Wisconsin Governor Hacks the Veto Process

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/wisconsin-governor-hacks-the-veto-process.html

In my latest book, A Hacker’s Mind, I wrote about hacks as loophole exploiting. This is a great example: The Wisconsin governor used his line-item veto powers—supposedly unique in their specificity—to change a one-year funding increase into a 400-year funding increase.

He took this wording:

Section 402. 121.905 (3) (c) 9. of the statues is created to read: 121.903 (3) (c) 9. For the limit for the 2023-24 school year and the 2024-25 school year, add $325 to the result under par. (b).

And he deleted these words, numbers, and punctuation marks:

Section 402. 121.905 (3) (c) 9. of the statues is created to read: 121.903 (3) (c) 9. For the limit for the 2023-24 school year and the 202425 school year, add $325 to the result under par. (b).

Seems to be legal:

Rick Champagne, director and general counsel of the nonpartisan Legislative Reference Bureau, said Evers’ 400-year veto is lawful in terms of its form because the governor vetoed words and digits.

“Both are allowable under the constitution and court decisions on partial veto. The hyphen seems to be new, but the courts have allowed partial veto of punctuation,” Champagne said.

Definitely a hack. This is not what anyone thinks about when they imagine using a line-item veto.

And it’s not the first time. I don’t know the details, but this was certainly the same sort of character-by-character editing:

Mr Evers’ Republican predecessor once deploying it to extend a state programme’s deadline by one thousand years.

A couple of other things:

One, this isn’t really a 400-year change. Yes, that’s what the law says. But it can be repealed. And who knows that a dollar will be worth—or if they will even be used—that many decades from now.

And two, from now all Wisconsin lawmakers will have to be on the alert for this sort of thing. All contentious bills will be examined for the possibility of this sort of delete-only rewriting. This sentence could have been reworded, for example:

For the 2023-2025 school years, add $325 to the result under par. (b).

The problem is, of course, that legalese developed over the centuries to be extra wordy in order to limit disputes. If lawmakers need to state things in the minimal viable language, that will increase court battles later. And that’s not even enough. Bills can be thousands of words long. If any arbitrary characters can be glued together by deleting enough other characters, bills can say anything the governor wants.

The real solution is to return the line-item veto to what we all think it is: the ability to remove individual whole provisions from a law before signing it.

Running GitHub Actions in a private Subnet with AWS CodeBuild

Post Syndicated from original https://aws.amazon.com/blogs/devops/running-github-actions-in-a-private-subnet-with-aws-codebuild/

Last week the Developer Tools team announced that AWS CodeBuild now supports GitHub Actions. AWS CodeBuild is a fully managed continuous integration service that allows you to build and test code. CodeBuild builds are defined as a collection of build commands and related settings, in YAML format, called a BuildSpec. You can now define GitHub Actions steps directly in the BuildSpec and run them alongside CodeBuild commands. In this post, I will use the Liquibase GitHub Action to deploy changes to an Amazon Aurora database in a private subnet.

Background

The GitHub Marketplace includes a large catalog of actions developed by third-parties and the open-source community. At the time of writing, there are nearly 20,000 actions available in the marketplace. Using an action from the marketplace can save you time and effort that would be spent scripting the installation and configuration of various tools required in the build process.

While I love GitHub actions, I often what to run my build in AWS. For example, I might want to access a resource in a private VPC or simply reduce the latency between the build service and my resources. I could accomplish this by hosting a GitHub Action Runner on Amazon Elastic Compute Cloud (Amazon EC2). However, hosting a GitHub Action runner requires additional effort to configure and maintain the environment that hosts the runner.

AWS CodeBuild is a fully managed continuous integration service. CodeBuild does not require ongoing maintenance and it can access resources in a private subnet. You can now use GitHub Actions in AWS CodeBuild. This feature provides the simplified configuration and management of CodeBuild with the rich marketplace of GitHub Actions. In the following section, I will explain how to configure CodeBuild to run a GitHub Action.

Walkthrough

In this walkthrough, I will configure AWS CodeBuild to use the Liquibase GitHub Action to deploy changelogs to a PostgreSQL database hosted on Amazon Aurora in a private subnet. As shown in the following image, AWS CodeBuild will be configured to run in a private subnet along with my Aurora instance. First, CodeBuild will download the GitHub action using a NAT Gateway to access the internet. Second, CodeBuild will apply the changelog to the Aurora instance in the private subnet.

Architecture diagram showing CodeBuild and Aurora in a private subnet with internet access provided by a NAT gateway

I already have a GitHub repository with the Liquibase configuration properties and changelogs shown in the following image. Liquibase configuration is not the focus of this blog post, but you can read more in Getting Started with Liquibase. My source also includes the buildspec.yaml file which I will explain later in this post.

GitHub repository with Liquibase change set

To create my build project, I open CodeBuild in the AWS Console and select Create build project. Then I provide a name and optional description for the build. My project is named liquibase-blog-post.

If you are note already connected to GitHub, you can connect using a personal access token as shown in the following image.

GitHub configuration in CodeBuild showing the GitHub personal access token

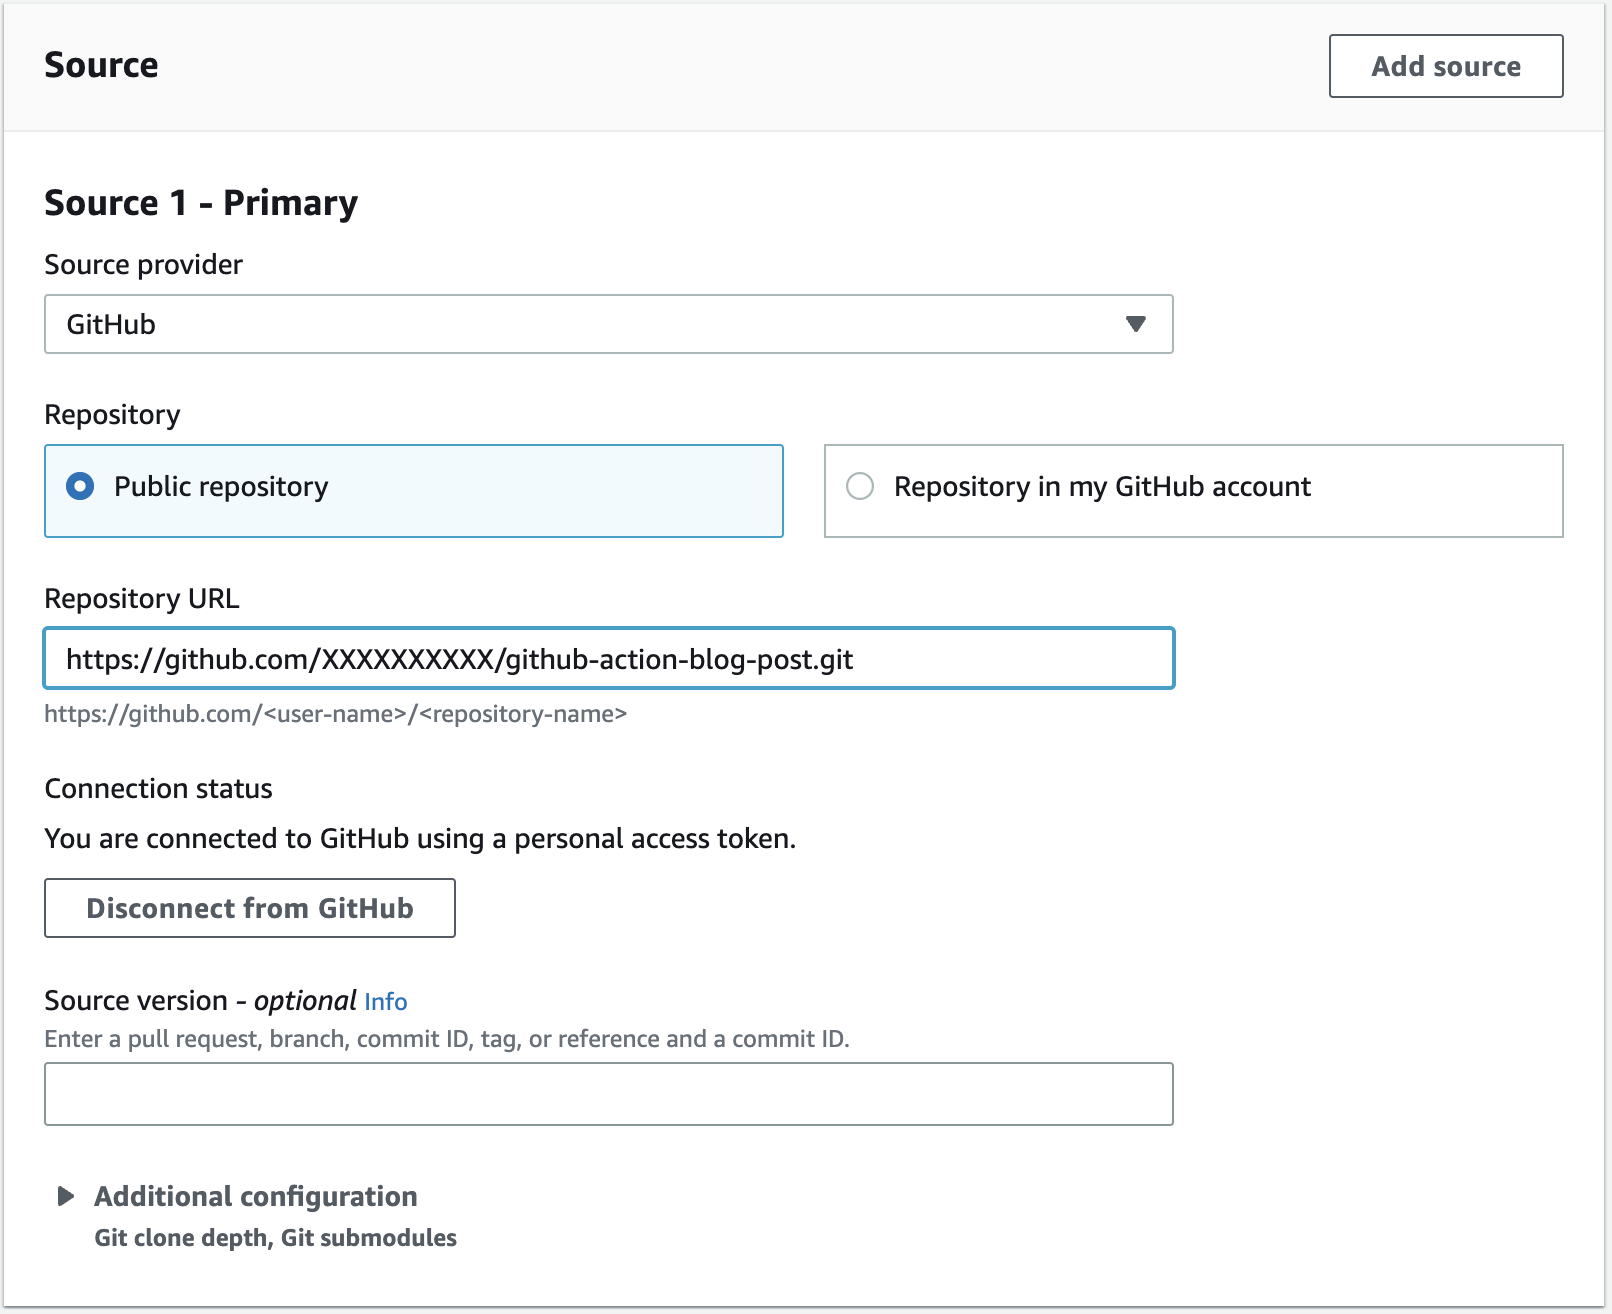
Once I have successfully connected to GitHub, I can paste the URL to my repository as shown in the following image.

CodeBuild configuration showing the GitHub repository URL

I configure my build environment to use the standard build environment on Amazon Linux 2. GitHub actions are built using either JavaScript or a Docker container. If the action uses a Docker container, you must enable the Privileged flag. The Liquibase image is using a Docker container, therefore, I check the box to enabled privileged mode.

Environment configuration showing the standard image on Linux and the privileged flag enabled.

For the VPC configuration, I select the VPC and private subnet where my Aurora instance is hosted and then click Validate VPC Settings to ensure my configuration is correct.

VPC configuration with private subnet selected

My Buildspec file is included I the source. Therefore, I select Use a buildspec file and enter the path to the buildspec file in the repository.

Buildspec configuration with Use a build spec file selected

My buildspec.yaml file includes the following content. Notice that the pre_build phase incudes a series of commands. Commands have always been supported in CodeBuild and include a series of command line commands to run. In this case, I am simply logging a few environment variables for later debugging.

version: 0.2
phases:
  pre_build:
    commands:
      - echo $AWS_DEFAULT_REGION
      - echo $URL
  build: 
    steps:
      - uses: liquibase-github-actions/[email protected]
        with:
          changelogFile: changelog-root.xml
          url: ${{ env.URL }}
          username: postgres
          password: ${{ $env.PASSWORD }}
          headless: true

Also notice that the build phase incudes a series of steps. Steps are new, and are used to run GitHub Actions. Each build phase supports either a list of commands, or a list of steps, but not both. In this example, I am specifying the Liquibase Update Action (liquibase-github-actions/update) with a few configuration parameters. You can see a full list of parameters in the Liquibase Update Action repository on GitHub.

I want to call you attention to the environment variables used in my buildspec.yml. Note that I pass the URL and PASSWORD for my database as environment variables. This allows me easily change these values from one environment to another. I have configured these environment variables in the CodeBuild project definition as shown in the following image. The URL is configured as Plaintext and the PASSWORD is configured as Secrets Manager. Running the GitHub Action in CodeBuild has the added advantage that I easily access secrets stored in AWS Secrets Manager and configuration data stored in AWS Systems Manager Parameter Store.

Environment Variables used to configure the URL and PASSWORD.

It is also important to note that the syntax use to access environment variables in the buildspec.yaml is different when using a GitHub Action. GitHub Actions access environment variables using the environment context. Therefore, in the pre_build phase, I am using CodeBuild syntax, in the format $NAME. However, the in the build phase, I am using GitHub syntax, in the format ${{ env:NAME}}.

With the configuration complete, I select Create build project and then manually start a build to test the configuration. In the following example you can see the logs from the Liquibase update. Notice that two changesets have been successfully applied to the database.


####################################################
##   _     _             _ _                      ##
##  | |   (_)           (_) |                     ##
##  | |    _  __ _ _   _ _| |__   __ _ ___  ___   ##
##  | |   | |/ _` | | | | | '_ \ / _` / __|/ _ \  ##
##  | |___| | (_| | |_| | | |_) | (_| \__ \  __/  ##
##  \_____/_|\__, |\__,_|_|_.__/ \__,_|___/\___|  ##
##              | |                               ##
##              |_|                               ##
##                                                ##
##  Get documentation at docs.liquibase.com       ##
##  Get certified courses at learn.liquibase.com  ##
##  Free schema change activity reports at        ##
##      https://hub.liquibase.com                 ##
##                                                ##
####################################################
Starting Liquibase at 18:33:23 (version 4.21.1 #9070)
Liquibase Version: 4.21.1
Liquibase Open Source 4.21.1 by Liquibase
Running Changeset: changelogs/changelog-1.0.0.xml::1::BobR
Running Changeset: changelogs/changelog-1.0.1.xml::2::BobR
  
UPDATE SUMMARY
Run: 2
Previously run: 0
Filtered out: 0
-------------------------------
Total change sets: 2
  
Liquibase: Update has been successful.
Liquibase command 'update' was executed successfully.
  
Phase complete: BUILD State: SUCCEEDED
Phase context status code: Message:
Entering phase POST_BUILD

If I connect to the Aurora database and describe the tables you can see that Liquibase has created the actor table (as defined in the Liquibase Quick Start) along with the Liquibase audit tables databasechangelog and databasechangeloglock. Everything is working just as I expected, and I did not have to install and configure Liquibase!


mydatabase=> \dt
List of relations
Schema  |         Name          | Type  |  Owner
--------+-----------------------+-------+----------
public  | actor                 | table | postgres
public  | databasechangelog     | table | postgres
public  | databasechangeloglock | table | postgres
(3 rows)

In this example, I showed you how to update an Aurora database in a private subnet using a the Liquibase GitHub Action running in CodeBuild. GitHub Actions provide a rich catalog of preconfigured actions simplifying the configuration. CodeBuild provides a managed service that simplifies the configuration and maintenance of my build environment. Used together I can get the best features of both CodeBuild and GitHub Actions.

Cleanup

In this walkthrough I showed you how to create a CodeBuild project. If you no longer need the project, you can simply delete it in the console. If you created other resources, for example an Aurora database, that were not explained in this post, you should delete those as well.

Conclusion

The GitHub Marketplace includes a catalog of nearly 20,000 actions developed by third-parties and the open-source community. AWS CodeBuild is a fully managed continuous integration service that integrates tightly with other AWS services. In this post I used the GitHub Action for Liquibase to deploy an update to a database in a private subnet. I am excited to see what you will do with support for GitHub Actions in CodeBuild. You can read more about this exciting new feature in GitHub Action runner in AWS CodeBuild.

Friday Squid Blogging: Giant Squid Nebula

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/friday-squid-blogging-giant-squid-nebula.html

Pretty:

A mysterious squid-like cosmic cloud, this nebula is very faint, but also very large in planet Earth’s sky. In the image, composed with 30 hours of narrowband image data, it spans nearly three full moons toward the royal constellation Cepheus. Discovered in 2011 by French astro-imager Nicolas Outters, the Squid Nebula’s bipolar shape is distinguished here by the telltale blue-green emission from doubly ionized oxygen atoms. Though apparently surrounded by the reddish hydrogen emission region Sh2-129, the true distance and nature of the Squid Nebula have been difficult to determine. Still, a more recent investigation suggests Ou4 really does lie within Sh2-129 some 2,300 light-years away. Consistent with that scenario, the cosmic squid would represent a spectacular outflow of material driven by a triple system of hot, massive stars, cataloged as HR8119, seen near the center of the nebula. If so, this truly giant squid nebula would physically be over 50 light-years across.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

The AI Dividend

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/the-ai-dividend.html

For four decades, Alaskans have opened their mailboxes to find checks waiting for them, their cut of the black gold beneath their feet. This is Alaska’s Permanent Fund, funded by the state’s oil revenues and paid to every Alaskan each year. We’re now in a different sort of resource rush, with companies peddling bits instead of oil: generative AI.

Everyone is talking about these new AI technologies—like ChatGPT—and AI companies are touting their awesome power. But they aren’t talking about how that power comes from all of us. Without all of our writings and photos that AI companies are using to train their models, they would have nothing to sell. Big Tech companies are currently taking the work of the American people, without our knowledge and consent, without licensing it, and are pocketing the proceeds.

You are owed profits for your data that powers today’s AI, and we have a way to make that happen. We call it the AI Dividend.

Our proposal is simple, and harkens back to the Alaskan plan. When Big Tech companies produce output from generative AI that was trained on public data, they would pay a tiny licensing fee, by the word or pixel or relevant unit of data. Those fees would go into the AI Dividend fund. Every few months, the Commerce Department would send out the entirety of the fund, split equally, to every resident nationwide. That’s it.

There’s no reason to complicate it further. Generative AI needs a wide variety of data, which means all of us are valuable—not just those of us who write professionally, or prolifically, or well. Figuring out who contributed to which words the AIs output would be both challenging and invasive, given that even the companies themselves don’t quite know how their models work. Paying the dividend to people in proportion to the words or images they create would just incentivize them to create endless drivel, or worse, use AI to create that drivel. The bottom line for Big Tech is that if their AI model was created using public data, they have to pay into the fund. If you’re an American, you get paid from the fund.

Under this plan, hobbyists and American small businesses would be exempt from fees. Only Big Tech companies—those with substantial revenue—would be required to pay into the fund. And they would pay at the point of generative AI output, such as from ChatGPT, Bing, Bard, or their embedded use in third-party services via Application Programming Interfaces.

Our proposal also includes a compulsory licensing plan. By agreeing to pay into this fund, AI companies will receive a license that allows them to use public data when training their AI. This won’t supersede normal copyright law, of course. If a model starts producing copyright material beyond fair use, that’s a separate issue.

Using today’s numbers, here’s what it would look like. The licensing fee could be small, starting at $0.001 per word generated by AI. A similar type of fee would be applied to other categories of generative AI outputs, such as images. That’s not a lot, but it adds up. Since most of Big Tech has started integrating generative AI into products, these fees would mean an annual dividend payment of a couple hundred dollars per person.

The idea of paying you for your data isn’t new, and some companies have tried to do it themselves for users who opted in. And the idea of the public being repaid for use of their resources goes back to well before Alaska’s oil fund. But generative AI is different: It uses data from all of us whether we like it or not, it’s ubiquitous, and it’s potentially immensely valuable. It would cost Big Tech companies a fortune to create a synthetic equivalent to our data from scratch, and synthetic data would almost certainly result in worse output. They can’t create good AI without us.

Our plan would apply to generative AI used in the US. It also only issues a dividend to Americans. Other countries can create their own versions, applying a similar fee to AI used within their borders. Just like an American company collects VAT for services sold in Europe, but not here, each country can independently manage their AI policy.

Don’t get us wrong; this isn’t an attempt to strangle this nascent technology. Generative AI has interesting, valuable, and possibly transformative uses, and this policy is aligned with that future. Even with the fees of the AI Dividend, generative AI will be cheap and will only get cheaper as technology improves. There are also risks—both every day and esoteric—posed by AI, and the government may need to develop policies to remedy any harms that arise.

Our plan can’t make sure there are no downsides to the development of AI, but it would ensure that all Americans will share in the upsides—particularly since this new technology isn’t possible without our contribution.

This essay was written with Barath Raghavan, and previously appeared on Politico.com.

Building Generative AI into Marketing Strategies: A Primer

Post Syndicated from nnatri original https://aws.amazon.com/blogs/messaging-and-targeting/building-generative-ai-into-marketing-strategies-a-primer/

Introduction

Artificial Intelligence has undoubtedly shaped many industries and is poised to be one of the most transformative technologies in the 21st century. Among these is the field of marketing where the application of generative AI promises to transform the landscape. This blog post explores how generative AI can revolutionize marketing strategies, offering innovative solutions and opportunities.

According to Harvard Business Review, marketing’s core activities, such as understanding customer needs, matching them to products and services, and persuading people to buy, can be dramatically enhanced by AI. A 2018 McKinsey analysis of more than 400 advanced use cases showed that marketing was the domain where AI would contribute the greatest value. The ability to leverage AI can not only help automate and streamline processes but also deliver personalized, engaging content to customers. It enhances the ability of marketers to target the right audience, predict consumer behavior, and provide personalized customer experiences. AI allows marketers to process and interpret massive amounts of data, converting it into actionable insights and strategies, thereby redefining the way businesses interact with customers.

Generating content is just one part of the equation. AI-generated content, no matter how good, is useless if it does not arrive at the intended audience at the right point of time. Integrating the generated content into an automated marketing pipeline that not only understands the customer profile but also delivers a personalized experience at the right point of interaction is also crucial to getting the intended action from the customer.

Amazon Web Services (AWS) provides a robust platform for implementing generative AI in marketing strategies. AWS offers a range of AI and machine learning services that can be leveraged for various marketing use cases, from content creation to customer segmentation and personalized recommendations. Two services that are instrumental to delivering customer contents and can be easily integrated with other generative AI services are Amazon Pinpoint and Amazon Simple Email Service. By integrating generative AI with Amazon Pinpoint and Amazon SES, marketers can automate the creation of personalized messages for their customers, enhancing the effectiveness of their campaigns. This combination allows for a seamless blend of AI-powered content generation and targeted, data-driven customer engagement.

As we delve deeper into this blog post, we’ll explore the mechanics of generative AI, its benefits and how AWS services can facilitate its integration into marketing communications.

What is Generative AI?

Generative AI is a subset of artificial intelligence that leverages machine learning techniques to generate new data instances that resemble your training data. It works by learning the underlying patterns and structures of the input data, and then uses this understanding to generate new, similar data. This is achieved through the use of models like Generative Adversarial Networks (GANs), Variational Autoencoders (VAEs), and Transformer models.

What do Generative AI buzzwords mean?

In the world of AI, buzzwords are abundant. Terms like “deep learning”, “neural networks”, “machine learning”, “generative AI”, and “large language models” are often used interchangeably, but they each have distinct meanings. Understanding these terms is crucial for appreciating the capabilities and limitations of different AI technologies.

Machine Learning (ML) is a subset of AI that involves the development of algorithms that allow computers to learn from and make decisions or predictions based on data. These algorithms can be ‘trained’ on a dataset and then used to predict or classify new data. Machine learning models can be broadly categorized into supervised learning, unsupervised learning, semi-supervised learning, and reinforcement learning.

Deep Learning is a subset of machine learning that uses neural networks with many layers (hence “deep”) to model and understand complex patterns. These layers of neurons process different features, and their outputs are combined to produce a final result. Deep learning models can handle large amounts of data and are particularly good at processing images, speech, and text.

Generative AI refers specifically to AI models that can generate new data that mimic the data they were trained on. This is achieved through the use of models like Generative Adversarial Networks (GANs) and Variational Autoencoders (VAEs). Generative AI can create anything from written content to visual designs, and even music, making it a versatile tool in the hands of marketers.

Large Language Models (LLMs) are a type of generative AI that are trained on a large corpus of text data and can generate human-like text. They predict the probability of a word given the previous words used in the text. They are particularly useful in applications like text completion, translation, summarization, and more. While they are a type of generative AI, they are specifically designed for handling text data.

Simply put, you can understand that Large Language Model is a subset of Generative AI, which is then a subset of Machine Learning and they ultimately falls under the umbrella term of Artificial Intelligence.

What are the problems with generative AI and marketing?

While generative AI holds immense potential for transforming marketing strategies, it’s important to be aware of its limitations and potential pitfalls, especially when it comes to content generation and customer engagement. Here are some common challenges that marketers should be aware of:

Bias in Generative AI Generative AI models learn from the data they are trained on. If the training data is biased, the AI model will likely reproduce these biases in its output. For example, if a model is trained primarily on data from one demographic, it may not accurately represent other demographics, leading to marketing campaigns that are ineffective or offensive. Imagine if you are trying to generate an image for a campaign targeting females, a generative AI model might not generate images of females in jobs like doctors, lawyers or judges, leading your campaign to suffer from bias and uninclusiveness.

Insensitivity to Cultural Nuances Generative AI models may not fully understand cultural nuances or sensitive topics, which can lead to content that is insensitive or even harmful. For instance, a generative AI model used to create social media posts for a global brand may inadvertently generate content that is seen as disrespectful or offensive by certain cultures or communities.

Potential for Inappropriate or Offensive Content Generative AI models can sometimes generate content that is inappropriate or offensive. This is often because the models do not fully understand the context in which certain words or phrases should be used. It’s important to have safeguards in place to review and approve content before it’s published. A common problem with LLMs is hallucination: whereby the model speaks false knowledge as if it is accurate. A marketing team might mistakenly publish a auto-generated promotional content that contains a 20% discount on an item when no such promotions were approved. This could have disastrous effect if safeguards are not in place and erodes customers’ trust.

Intellectual Property and Legal Concerns Generative AI models can create new content, such as images, music, videos, and text, which raises questions of ownership and potential copyright infringement. Being a relatively new field, legal discussions are still ongoing to discuss legal implications of using Generative AI, e.g. who should own generated AI content, and copyright infringement.

Not a Replacement for Human Creativity Finally, while generative AI can automate certain aspects of marketing campaigns, it cannot replace the creativity or emotional connections that marketers use in crafting compelling campaigns. The most successful marketing campaigns touch the hearts of the customers, and while Generative AI is very capable of replicating human content, it still lacks in mimicking that “human touch”.

In conclusion, while generative AI offers exciting possibilities for marketing, it’s important to approach its use with a clear understanding of its limitations and potential pitfalls. By doing so, marketers can leverage the benefits of generative AI while mitigating risks.

How can I use generative AI in marketing communications?

Amazon Web Services (AWS) provides a comprehensive suite of services that facilitate the use of generative AI in marketing. These services are designed to handle a variety of tasks, from data processing and storage to machine learning and analytics, making it easier for marketers to implement and benefit from generative AI technologies.

Overview of Relevant AWS Services

AWS offers several services that are particularly relevant for generative AI in marketing:

  • Amazon Bedrock: This service makes FMs accessible via an API. Bedrock offers the ability to access a range of powerful FMs for text and images, including Amazon’s Titan FMs. With Bedrock’s serverless experience, customers can easily find the right model for what they’re trying to get done, get started quickly, privately customize FMs with their own data, and easily integrate and deploy them into their applications using the AWS tools and capabilities they are familiar with.
  • Amazon Titan Models: These are two new large language models (LLMs) that AWS is announcing. The first is a generative LLM for tasks such as summarization, text generation, classification, open-ended Q&A, and information extraction. The second is an embeddings LLM that translates text inputs into numerical representations (known as embeddings) that contain the semantic meaning of the text. In response to the pitfalls mentioned above around Generative AI hallucinations and inaccurate information, AWS is actively working on improving accuracy and ensuring its Titan models produce high-quality responses, said Bratin Saha, an AWS vice president.
  • Amazon SageMaker: This fully managed service enables data scientists and developers to build, train, and deploy machine learning models quickly. SageMaker includes modules that can be used for generative AI, such as Generative Adversarial Networks (GANs) and Variational Autoencoders (VAEs).
  • Amazon Pinpoint: This flexible and scalable outbound and inbound marketing communications service enables businesses to engage with customers across multiple messaging channels. Amazon Pinpoint is designed to scale with your business, allowing you to send messages to a large number of users in a short amount of time. It integrates with AWS’s generative AI services to enable personalized, AI-driven marketing campaigns.
  • Amazon Simple Email Service (SES): This cost-effective, flexible, and scalable email service enables marketers to send transactional emails, marketing messages, and other types of high-quality content to their customers. SES integrates with other AWS services, making it easy to send emails from applications being hosted on services such as Amazon EC2. SES also works seamlessly with Amazon Pinpoint, allowing for the creation of customer engagement communications that drive user activity and engagement.

How to build Generative AI into marketing communications

Dynamic Audience Targeting and Segmentation: Generative AI can help marketers to dynamically target and segment their audience. It can analyze customer data and behavior to identify patterns and trends, which can then be used to create more targeted marketing campaigns. Using Amazon Sagemaker or the soon-to-be-available Amazon Bedrock and Amazon Titan Models, Generative AI can suggest labels for customers based on unstructured data. According to McKinsey, generative AI can analyze data and identify consumer behavior patterns to help marketers create appealing content that resonates with their audience.

Personalized Marketing: Generative AI can be used to automate the creation of marketing content. This includes generating text for blogs, social media posts, and emails, as well as creating images and videos. This can save marketers a significant amount of time and effort, allowing them to focus on other aspects of their marketing strategy. Where it really shines is the ability to productionize marketing content creation, reducing the needs for marketers to create multiple copies for different customer segments. Previously, marketers would need to generate many different copies for each granularity of customers (e.g. attriting customers who are between the age of 25-34 and loves food). Generative AI can automate this process, providing the opportunities to dynamically create these contents programmatically and automatically send out to the most relevant segments via Amazon Pinpoint or Amazon SES.

Marketing Automation: Generative AI can automate various aspects of marketing, such as email marketing, social media marketing, and search engine marketing. This includes automating the creation and distribution of marketing content, as well as analyzing the performance of marketing campaigns. Amazon Pinpoint currently automates customer communications using journeys which is a customized, multi-step engagement experience. Generative AI could create a Pinpoint journey based on customer engagement data, engagement parameters and a prompt. This enables GenAI to not only personalize the content but create a personalized omnichannel experience that can extend throughout a period of time. It then becomes possible that journeys are created dynamically by generative AI and A/B tested on the fly to achieve an optimal pre-defined Key Performance Indicator (KPI).

A Sample Generative AI Use Case in Marketing Communications

AWS services are designed to work together, making it easy to implement generative AI in your marketing strategies. For instance, you can use Amazon SageMaker to build and train your generative AI models which assist with automating marketing content creation, and Amazon Pinpoint or Amazon SES to deliver the content to your customers.

Companies using AWS can theoretically supplement their existing workloads with generative AI capabilities without the needs for migration. The following reference architecture outlines a sample use case and showcases how Generative AI can be integrated into your customer journeys built on the AWS cloud. An e-commerce company can potentially receive many complaints emails a day. Companies spend a lot of money to acquire customers, it’s therefore important to think about how to turn that negative experience into a positive one.

GenAIMarketingSolutionArchitecture

When an email is received via Amazon SES (1), its content can be passed through to generative AI models using GANs to help with sentiment analysis (2). An article published by Amazon Science utilizes GANs for sentiment analysis for cases where a lack of data is a problem. Alternatively, one can also use Amazon Comprehend at this step and run A/B tests between the two models. The limitations with Amazon Comprehend would be the limited customizations you can perform to the model to fit your business needs.

Once the email’s sentiment is determined, the sentiment event is logged into Pinpoint (3), which then triggers an automatic winback journey (4).

Generative AI (e.g. HuggingFace’s Bloom Text Generation Models) can again be used here to dynamically create the content without needing to wait for the marketer’s input (5). Whereas marketers would need to generate many different copies for each granularity of customers (e.g. attriting customers who are between the age of 25-34 and loves food), generative AI provides the opportunities to dynamically create these contents on the fly given the above inputs.

Once the campaign content has been generated, the model pumps the template backs into Amazon Pinpoint (6), which then sends the personalized copy to the customer (7).

Result: Another customer is saved from attrition!

Conclusion

The landscape of generative AI is vast and ever-evolving, offering a plethora of opportunities for marketers to enhance their strategies and deliver more personalized, engaging content. AWS plays a pivotal role in this landscape, providing a comprehensive suite of services that facilitate the implementation of generative AI in marketing. From building and training AI models with Amazon SageMaker to delivering personalized messages with Amazon Pinpoint and Amazon SES, AWS provides the tools and infrastructure needed to harness the power of generative AI.

The potential of generative AI in relation to the marketer is immense. It offers the ability to automate content creation, personalize customer interactions, and derive valuable insights from data, among other benefits. However, it’s important to remember that while generative AI can automate certain aspects of marketing, it is not a replacement for human creativity and intuition. Instead, it should be viewed as a tool that can augment human capabilities and free up time for marketers to focus on strategy and creative direction.

Get started with Generative AI in marketing communications

As we conclude this exploration of generative AI and its applications in marketing, we encourage you to:

  • Brainstorm potential Generative AI use cases for your business. Consider how you can leverage generative AI to enhance your marketing strategies. This could involve automating content creation, personalizing customer interactions, or deriving insights from data.
  • Start leveraging generative AI in your marketing strategies with AWS today. AWS provides a comprehensive suite of services that make it easy to implement generative AI in your marketing strategies. By integrating these services into your workflows, you can enhance personalization, improve customer engagement, and drive better results from your campaigns.
  • Watch out for the next part in the series of integrating Generative AI into Amazon Pinpoint and SES. We will delve deeper into how you can leverage Amazon Pinpoint and SES together with generative AI to enhance your marketing campaigns. Stay tuned!

The journey into the world of generative AI is just beginning. As technology continues to evolve, so too will the opportunities for marketers to leverage AI to enhance their strategies and deliver more personalized, engaging content. We look forward to exploring this exciting frontier with you.

About the Author

Tristan (Tri) Nguyen

Tristan (Tri) Nguyen

Tristan (Tri) Nguyen is an Amazon Pinpoint and Amazon Simple Email Service Specialist Solutions Architect at AWS. At work, he specializes in technical implementation of communications services in enterprise systems and architecture/solutions design. In his spare time, he enjoys chess, rock climbing, hiking and triathlon.
Belgian Tax Hack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/belgian-tax-hack.html

Here’s a fascinating tax hack from Belgium (listen to the details here, episode #484 of “No Such Thing as a Fish,” at 28:00).

Basically, it’s about a music festival on the border between Belgium and Holland. The stage was in Holland, but the crowd was in Belgium. When the copyright collector came around, they argued that they didn’t have to pay any tax because the audience was in a different country. Supposedly it worked.

AWS Application Migration Service Major Updates: Global View, Import and Export from Local Disk, and Additional Post-launch Actions

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/aws-application-migration-service-major-updates-global-view-import-and-export-from-local-disk-and-additional-post-launch-actions/

AWS Application Migration Service simplifies, expedites, and reduces the cost of migrating your applications to AWS. It allows you to lift and shift many physical, virtual, or cloud servers without compatibility issues, performance disruption, or long cutover windows. You can minimize time-intensive, error-prone manual processes by automating replication and conversion of your source servers from physical, virtual, or cloud infrastructure to run natively on AWS by using Application Migration Service for migration. Earlier this year, we introduced major improvements, such as a server migration metrics dashboard, import and export, and additional post-launch modernization actions.

Today, I’m pleased to announce three major updates to Application Migration Service. Here’s the quick summary for each feature release:

  • Global View – You can manage large-scale migrations across multiple accounts. This feature provides you both visibility and the ability to perform specific actions on source servers, apps, and waves in different AWS accounts.
  • Import and Export from Local Disk – You can now use Application Migration Service to import your source environment inventory list to the service from a CSV file on your local disk. You can also export your source server inventory list from the service to a CSV file and download it to your local disk. You can continue leveraging the previously launched import and export functionality to and from an S3 bucket.
  • Additional Post-launch Actions – In this update, Application Migration Service added four additional predefined post-launch actions. These actions are applied to your migrated applications when you launch them on AWS.

Let me share how you can use these features for your migration.

Global View
Global View provides you the visibility and the ability to perform specific actions on source servers, applications, and waves in different AWS accounts. Global view uses AWS Organizations to structure a management account (which has access to source servers in multiple member accounts) and member accounts (which only have access to their own source servers).

To use this feature, you need to have an AWS account in which AWS Application Migration Service is initialized. This account must be an admin in AWS Organizations or a delegated admin for AWS Application Migration Service. You can view the Global View page on the Application Migration Service page in the AWS Management Console by selecting Global View in the left navigation menu.

You can use the global view feature to see source servers, applications and waves across multiple managed accounts and perform various actions, including:

  • Launching test and cutover instances across accounts
  • Monitoring migration execution progress across accounts

The main Global View page provides an overview of your account and this information changes depending on whether you have a management account or a member account.

In a management account, you can see the AWS organizations permissions, the count of linked accounts, and the total number of source servers, applications, and waves under Account information. The Linked accounts section displays the relevant information for your linked accounts. It shows all the linked accounts this account has access to, including the account you’re logged into (the management account) and the member accounts that are linked to it. If the management account has access to two additional member accounts, the Linked accounts section will show three accounts. It’s the total number of accounts that are visible through this management account (including itself). For member accounts, this page only displays the account information that includes the AWS organizations permissions and the number of source servers, applications, and waves in the specific account.

Global view

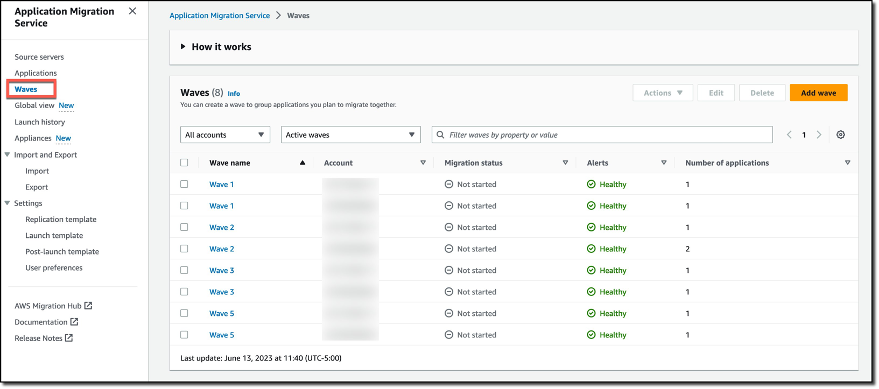
In your management account, you can access and review source servers, applications and waves within your account and across all member accounts. As a manager, you can choose between All accounts and My account from the drop-down menu, which allows you to change you view of presented source servers, applications or waves.

Waves

Import and Export from Local Disk
A comprehensive data center inventory forms the foundation of any successful migration endeavor. This inventory encompasses a comprehensive list of servers and applications managed by customers on premises. The inventory is categorized into migration waves to facilitate efficient migration planning.

Typically, this inventory is compiled using discovery tools or created manually by IT administrators. Perhaps you maintain your data center inventory in Excel spreadsheets. With Application Migration Service, we offer seamless support for importing your inventory list from a CSV file, which follows a format similar to the one used by Cloud Migration Factory.

In the previous release, Application Migration Service supported the option to import a file from Amazon S3 and export a file to Amazon S3. In this latest release, Application Migration Service supports the option to import a file from local disk and export a file to local disk. This makes it easy for you to manage large scale-migrations and ingest your inventory of source servers, applications and waves, including their attributes such as EC2 instance type, subnet and tags. These attributes are the parameters used to populate the EC2 launch template.

Import and Export

To start using the import feature, you need to identify your servers and application inventory. You can do this manually or using discovery tools. The next thing you need to do is download the import template, which you can access from the console.

Import Local

After you download the import template, you can start mapping your inventory list onto this template. While mapping your inventory, you can group related servers into applications and waves. You can also perform configurations, such as defining Amazon Elastic Compute Cloud (Amazon EC2) launch template settings and specifying tags for each wave.

The following screenshot is an example of the results of my import template.

Inventory

On the Application Migration Service page in the AWS Management Console, select Import on the left-side navigation menu (under Import and Export). Under the Import inventory tab, select Import from local disk. Select Choose file and choose the local file containing your inventory list. Select Import, and the inventory file is imported into Application Migration Service. When the import process is complete, the details of the import results appear.

Now, you can view all your inventory inside the Source servers, Applications, and Waves pages on the Application Migration Service console.

To export your inventory to a local file, select Export on the left-side navigation menu of the Application Migration Service page. Under Export inventory tab, choose Export to local disk. Specify the name of the file to download under Destination filename. Choose Export, and the inventory file downloads to your local disk. Application Migration Service uses an S3 bucket within your account for the import and export operations, even when using local disk. You must have the required permissions to perform this action. You can modify the exported inventory file and reimport it to perform bulk configuration updates across your inventory. When the global view feature is activated upon reimport, configuration changes are applied also across accounts.

Export Local

Additional Post-launch Actions
Post-launch actions allow you to control and automate actions performed after your servers have been launched in AWS. You can use predefined or custom post-launch actions.

Application Migration Service now has four additional predefined post-launch actions to run in your Amazon EC2 instances on top of the existing predefined post-launch actions. These additional post-launch actions provide you with flexibility to maximize your migration experience.

Post Launch template

The new four additional predefined post-launch actions are as follows:

  • Configure Time Sync – You can use the Time Sync feature to set the time for your Linux instance using ATSS.
  • Validate disk space – You can use the disk space validation feature to obtain visibility into the disk space and to ensure that you have enough available disk space on your target server.
  • Verify HTTP(S) response – You can use the Verify HTTP(S) response feature to conduct HTTP(S) connectivity checks to a predefined list of URLs. The feature verifies the connectivity to the launched target instance.
  • Enable Amazon Inspector – The Enable Amazon Inspector feature allows you to run security scans on your Amazon EC2 resources, including the target instances launched by Application Migration Service. The Amazon Inspector service is enabled at the account level. This action uses the Enable, BatchGetAccountStatus, and CreateServiceLinkedRole APIs.

Now Available
The Global View, Import and Export Feature from Local, and Additional Post-launch Actions are available now, and you can start using them today in all Regions where AWS Application Migration Service is supported. Visit the Application Migration Service User Guide to dive deeper into these exciting features and you can refer to the Getting started with AWS Application Migration Service to kickstart your workload migration to AWS.

—Irshad

Class-Action Lawsuit for Scraping Data without Permission

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/class-action-lawsuit-for-scraping-data-without-permission.html

I have mixed feelings about this class-action lawsuit against OpenAI and Microsoft, claiming that it “scraped 300 billion words from the internet” without either registering as a data broker or obtaining consent. On the one hand, I want this to be a protected fair use of public data. On the other hand, I want us all to be compensated for our uniquely human ability to generate language.

There’s an interesting wrinkle on this. A recent paper showed that using AI generated text to train another AI invariably “causes irreversible defects.” From a summary:

The tails of the original content distribution disappear. Within a few generations, text becomes garbage, as Gaussian distributions converge and may even become delta functions. We call this effect model collapse.

Just as we’ve strewn the oceans with plastic trash and filled the atmosphere with carbon dioxide, so we’re about to fill the Internet with blah. This will make it harder to train newer models by scraping the web, giving an advantage to firms which already did that, or which control access to human interfaces at scale. Indeed, we already see AI startups hammering the Internet Archive for training data.

This is the same idea that Ted Chiang wrote about: that ChatGPT is a “blurry JPEG of all the text on the Web.” But the paper includes the math that proves the claim.

What this means is that text from before last year—text that is known human-generated—will become increasingly valuable.

AWS Week in Review – Generative AI with LLM Hands-on Course, Amazon SageMaker Data Wrangler Updates, and More – July 3, 2023

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-week-in-review-generative-ai-with-llm-hands-on-course-amazon-sagemaker-data-wrangler-updates-and-more-july-3-2023/

In last week’s AWS Week in Review post, Danilo mentioned that it’s summer in London. Well, I’m based in Singapore, and it’s mostly summer here. But, June is a special month here as it marks the start of durian season.

Starting next week, I’ll be travelling to Thailand, Malaysia, and the Philippines. But before I go, I want to share some interesting updates from last week for you.

Let’s get started.

Last Week’s Launches
Here are some launches that caught my attention:

New Hands-on Course: Generative AI with Large Language Models – Generative AI has been a technology highlight for the past few months. If you are on your journey to learn large language models (LLM), then you can try the new hands-on course Generative AI with LLMs at Coursera. Antje wrote a post to announce this collaboration course between DeepLearning.AI and AWS. This course is designed to prepare data scientists and engineers to become experts in selecting, training, fine-tuning, and deploying LLMs for real-world applications.

Generative AI with large language models

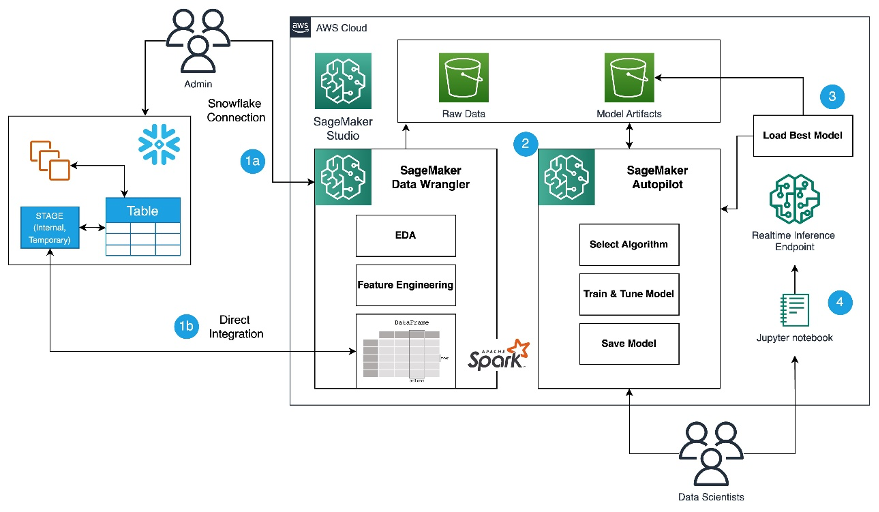
Amazon SageMaker Data Wrangler direct connection to Snowflake – With this announcement, you can now browse databases, tables, schemas, and query data from Snowflake in SageMaker Data Wrangler. This unlocks the possibility for you to join your data with other popular data sources, such as S3, Amazon Athena, Amazon Redshift, Amazon EMR and over 50 SaaS applications to create the right data set for machine learning.

Amazon SageMaker Role Manager now provides CDK library to create fine-grained permissions — The CDK support for Amazon SageMaker Role Manager lets you define permissions with fine-grained access for SageMaker users, jobs, and SageMaker pipelines programmatically. This will reduce manual efforts and consistent permissions management. For example, the following code grants permissions with a set of related machine learning activities specific to a persona.


export class myCDKStack extends cdk.Stack {
  constructor(scope: cdk.App, id: string, props?: cdk.StackProps) {
    super(scope, id, props);

    const persona = new Persona(this, 'example-persona-id', {
        activities: [
            Activity.runStudioAppsV2(this, 'example-id1', {}), 
            Activity.accessS3Buckets(this, 'example-id2', {s3buckets: [s3.S3Bucket.fromBucketName('DOC-EXAMPLE-BUCKET')]}) 
            Activity.accessAwsServices(this, 'example-id3', {})
        ]
    });

    const role = persona.createRole(this, 'example-IAM-role-id', 'example-IAM-role-name');
    
    }
}                                   
                

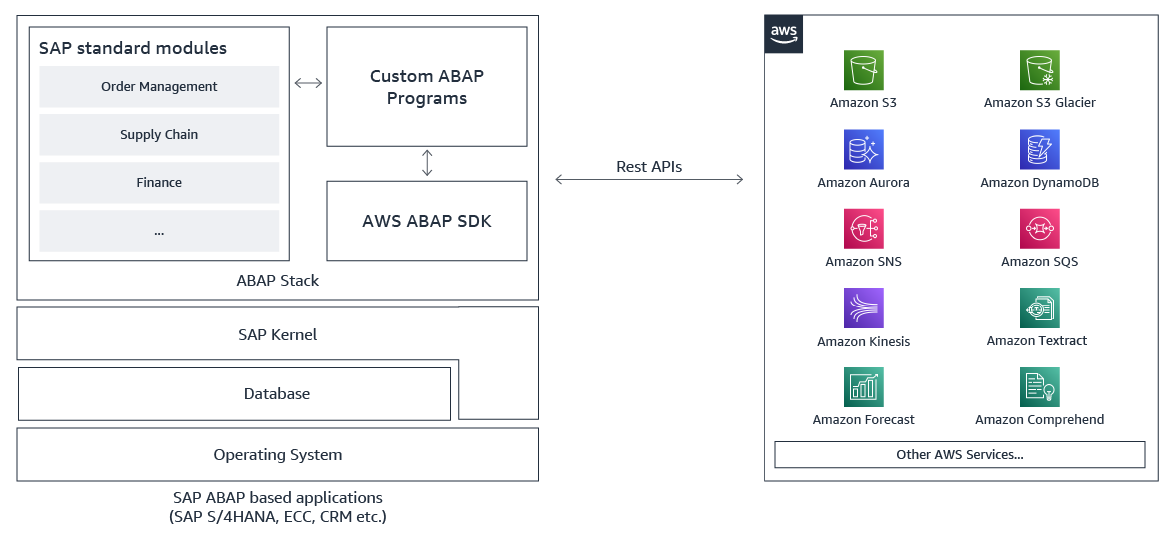
AWS SDK for SAP ABAP – Great news for SAP ABAP developers! We just recently announced the general availability of the AWS SDK for SAP ABAP. With this, ABAP developers can use simple, secure and configurable connections between ABAP environments and 200+ supported AWS services in all AWS Regions, including AWS GovCloud (US) Regions. This AWS SDK helps ABAP developers to modernize their business processes with AWS services.

Amazon OpenSearch Ingestion now supports ingesting events from Amazon Security Lake – Amazon OpenSearch Ingestion now lets you bring data in the Apache Parquet format. As Amazon Security Lake also uses Open Cybersecurity Schema Framework (OCSF) in Apache Parquet format, it means you can easily ingest data from Amazon Security Lake.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

AWS Open-Source Updates
As always, my colleague Ricardo has curated the latest updates for open-source news at AWS. Here are some of the highlights.

lightsail-miab-installer – This handy command-line tool developed by my colleague Rio Astamal was designed to simplify the process of setting up Mail-in-a-Box on Amazon Lightsail. With lightsail-miab-installer, you can effortlessly streamline the installation and configuration of Mail-in-a-Box, making it even more accessible and user-friendly.

rdsconn – This amazing tool, created by AWS Hero Aidan Steele, simplifies the process of connecting to an AWS RDS instance within a VPC directly from your laptop. Using the recently launched EC2 Instance Connect, rdsconn eliminates the need for cumbersome SSH tunnels.

cdk-appflow – If you’re using AWS CDK to build your applications and Amazon AppFlow to create bidirectional data transfer integrations between various SaaS applications and AWS, then you’re going to love cdk-appflow, a new AWS CDK construct for Amazon AppFlow. It’s currently in technical preview, but you’re more than welcome to try it and provide us with your feedback.

Upcoming AWS Events
There are also upcoming events that you can join to learn. Let’s start with AWS Summit events:

And, let’s learn from our fellow builders and join AWS Community Days:

Open for Registration for AWS re:Invent
Before I end this post, AWS re:Invent registration is now open!

This learning conference hosted by AWS for the global cloud computing community will be held from Nov 27 to Dec 1, 2023 in Las Vegas.

Pro-tip: You can use information on the Justify Your Trip page to prove the value of your trip to AWS re:Invent.

That’s all for this week. Check back next Monday for another Week in Review.

Happy building.
Donnie

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Self-Driving Cars Are Surveillance Cameras on Wheels

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/self-driving-cars-are-surveillance-cameras-on-wheels.html

Police are already using self-driving car footage as video evidence:

While security cameras are commonplace in American cities, self-driving cars represent a new level of access for law enforcement ­ and a new method for encroachment on privacy, advocates say. Crisscrossing the city on their routes, self-driving cars capture a wider swath of footage. And it’s easier for law enforcement to turn to one company with a large repository of videos and a dedicated response team than to reach out to all the businesses in a neighborhood with security systems.

“We’ve known for a long time that they are essentially surveillance cameras on wheels,” said Chris Gilliard, a fellow at the Social Science Research Council. “We’re supposed to be able to go about our business in our day-to-day lives without being surveilled unless we are suspected of a crime, and each little bit of this technology strips away that ability.”

[…]

While self-driving services like Waymo and Cruise have yet to achieve the same level of market penetration as Ring, the wide range of video they capture while completing their routes presents other opportunities. In addition to the San Francisco homicide, Bloomberg’s review of court documents shows police have sought footage from Waymo and Cruise to help solve hit-and-runs, burglaries, aggravated assaults, a fatal collision and an attempted kidnapping.

In all cases reviewed by Bloomberg, court records show that police collected footage from Cruise and Waymo shortly after obtaining a warrant. In several cases, Bloomberg could not determine whether the recordings had been used in the resulting prosecutions; in a few of the cases, law enforcement and attorneys said the footage had not played a part, or was only a formality. However, video evidence has become a lynchpin of criminal cases, meaning it’s likely only a matter of time.

Предпазване срещу радиоактивен йод

Post Syndicated from original http://www.gatchev.info/blog/?p=2592

Вече от поне две седмици от различни източници постъпва информация, че руската армия е минирала АЕЦ Запорижя на практика напълно. Повечето от източниците (напр. украинското разузнаване) са пристрастни и е разумно да не бъдат приемани с абсолютно безрезервно доверие. Има обаче източници, непублични и с ограничен достъп, които не са твърде пристрастни, а твърдят същото. Така че е разумно да се приеме, че е възможно (ако и не абсолютно сигурно) да е вярно.

А от няколко дни постъпват новини, че руската армия се изтегля тихомълком от АЕЦ-а. Досега тя го държеше под строг контрол – в централата по всяко време имаше сериозни по размер руски военни части, включително тежко въоръжение (танкове, ракетни установки…). От военна точка изтегляне не се налага, пунктът все още е далече от бойната линия. Едно от вероятните предположения е, че има опасност централата да стане източник на радиоактивно заразяване – поради взривяване на мините или по друга причина.

В тази връзка може би ще е полезно да знаем какво да правим, ако този най-лош сценарий се сбъдне. Ако пък не, знаенето няма да ни навреди.

Общи думи

Адекватните мерки при радиоактивно заразяване са различни, в зависимост от типа и силата на заразяването. Те пък зависят от вида на източника, разстоянието до него и други фактори.

Когато източникът е единичен (ядрен взрив, авария в АЕЦ…) и разстоянието е много стотици или хиляди километри, почти единствената опасност е от отделения радиоактивен йод (осноно изотоп 131). Той се натрупва в щитовидната жлеза на хората и животните и увеличава вероятността от рак в нея. Другите опасности от него или други радионуклиди в този случай обикновено са минимални. (При много лоши стечения на обстоятелствата могат да бъдат реални. Това описание не ги покрива.)

Опасността от йод-131 зависи от количеството му около нас. То – от общото отделено количество йод-131 и дали и колко от него е пренесено от мястото на инцидента към нас. При разстояние като това от България до АЕЦ Запорижя пренасянето зависи от атмосферните условия около и след инцидента.

Количеството отделен йод би зависело от какви и колко обекти в АЕЦ Запорижя са пострадали, и в каква степен. АЕЦ-ът има 6 реактора ВВЕР-1000, плюс сериозни като размер охладителни басейни за първично съхранение на отработеното ядрено гориво. Ако всички те пострадат сериозно, количеството отделен йод-131 може да е десетки пъти над отделеното при авариите в АЕЦ Чернобил и Фукушима, и хиляди пъти над отделеното при употреба на един или няколко тактически ядрени заряда. (Това не означава, че другите последствия непременно също ще бъдат толкова по-големи, или дори същите.)

Размерът на уврежданията при потенциален инцидент е невъзможно да се предскаже отсега, атмосферните условия – също. Затова давам съвет как да се действа срещу радиоактивния йод при най-лош вероятен вариант. (Ако се появи реална опасност и от други радионуклиди, това ще е тема за отделен запис.)

За щастие Енергодар е на много стотици километри от нас. Ако там се случи нещо, дори ако вятърът духа оттам насам (което е рядко), ще имаме време да научим. Ще имаме време и да разберем дали е отделена радиация, и ако да – дали е количество, което заслужава предпазни мерки. След това ще имаме време и да проверим дали вятърът го носи към нас или надругаде. И след това, ако се налага, ще имаме предостатъчно време да вземем предпазни мерки, без да сме закъснели. Дебело подчертавам – не взимайте предпазните мерки преди да е потвърдено, че се налага!

Защита срещу радиоактивен йод

Радиоактивният йод е опасен с това, че щитовидната ни жлеза го поема и натрупва точно както обикновения йод. (И с това се излага на лъчението от атомите му.) Ако тя бъде наситена с достатъчно йод преди радиоактивният да стигне до нас, тя няма да поема повече и съответно няма да поеме от радиоактивния.

Предпочитаното за насищане с йод средство е калиев йодид. Той е активното вещество във всички йодни хапчета. Химическият калиев йодид е точно същото – ако нямате йодни хапчета, но имате химически калиев йодид, можете да отмерите от него правилната доза. (Горчив е на вкус – можете да го приемете с ядене или някакъв подсладител, не му пречат. Може да подразни стомаха – добре е да се приема с храна, или поне с прясно или кисело мляко. Храната не пречи на резорбцията му.)

Ако нямате други варианти, йод може да се набави и от йодна тинктура. Тинктурата е разтвор на йод (често и калиев йодид) във вода, спирт или комбинация от двете. Какво съдържа и точното му количество трябва да са посочени на опаковката – ако не са, не я използвайте! Ако съдържа само или основно чист йод, занижете малко милиграмите (100 мг чист йод са приблизително еквивалентни на 126 мг калиев йодид). Вкусът ѝ също не е приятен.

Тинктурата може да бъде предпочитана при хора, които не могат да приемат йод през стомаха (напр. тежки стомашни проблеми или силно чувствителен стомах). При намазване по кожата в областта на корема обикновено се резорбира около 80% от йода в нея. (Вместо да пиете таблетка от 130 мг, можете да намажете колкото тинктура съдържа 160 мг. калиев йодид или 125 мг. йод. Типичната за България йодна тинктура съдържа 5% йод и 10% калиев йодид – 0.8 до 1 куб. см от нея е подходяща доза за 72 кг. тегло.) Не е страшно да намажете повече от необходимото – опасно за здравето количество няма да се резорбира. (Но по-чувствителна кожа може да се раздразни – внимавайте пък за това!)

Може да ви предложат в аптеката Йодасепт или друга търговска марка на повидон-йодин. За дезинфекция на рани е прекрасен, за насищане с йод – не. Йодът в него е 1%, 15 пъти по-малко, отколкото в йодна тинктура. При намазване върху кожата не е известно какъв процент се резорбира, възможно е да е близък до нулата. При вътрешно поглъщане може да отдели атомарен йод, който е силен дразнител, по-висока доза може да ви изгори стомаха. Не го пийте!

При опасност като описаната, правилната стратегия би била да се приема ежедневно доза йод до намаляване на опасността от радиоактивния йод до пренебрежима. Последното става, когато радиацията от него спадне до нива, сравними или по-ниски от тези на естествения радиационен фон. Периодът на полуразпад на йод-131 е 8 дни – тоест, на всеки 8 дни радиацията и опасността от него спадат наполовина. След 16 дни те ще са 1/4 от първоначалните, след 24 дни – 1/8, след 32 дни – 1/16 и т.н.

След десетия ден можете да намалите дозата двойно или да я приемате през ден – защитата остава на практика същата.

Добре е да започнете приема на йод поне няколко часа преди радоактивният да достигне до вас. Ако закъснеете с няколко часа или дори дни, пак си струва – по-малко предпазване е по-добре от никакво. Безсмислено е да се започва преди информация, че имаме авария с изхвърляне на радиоактивен йод – дори в идеални метеорологични условия той надали би достигнал от АЕЦ Запорижя до България за по-малко от денонощие. В типичния случай биха му трябвали 2 денонощия, а ако вятърът не го носи насам, не е изключено дори при сериозно изхвърляне дотук да не достигне опасно количество.

Оптималната доза калиев йодид зависи от теглото на индивида. Зависимостта обаче не е линейна: по-ниското тегло изисква повече калиев йодид на килограм. Ето таблица за приблизителните оптимални дози:

72 кг. – 130 мг. на ден

40-45 кг. – 65 мг. на ден.

20-30 кг. – 32-45 мг. на ден

10 кг. – 25 мг. на ден

5 кг. – 20 мг. на ден

3 кг. – 15 мг. на ден

Приемането на доза до 2 пъти оптималната обикновено е безопасно за организма – не се притеснявайте, ако не можете да я отмерите абсолютно точно. Изключение са алергичните на йод и йодни препарати – те е добре да се консултират с лекар по темата.

При болести на щитовидната жлеза тези дози може да не са адекватни. Например при болест на Хашимото може да са необходими по-ниски. Каква доза е подходяща за конкретния болен зависи от болестта и стадия ѝ – може да е от няколко пъти дадената до нулева. Задължително се консултирайте с лекаря си по въпроса!

Йодните хапчета са обикновено 2 грамажа – 130 мг. и 65 мг. Смятайте според какви имате.

Ако се налага да делите хапче (или отмерена доза калиев йодид), най-добре ги разтворете във вода. Сложете в чаша такъв брой лъжици, малки чашки или кубически сантиметри вода (ако имате с какво да ги мерите), какъвто после ще ви е най-лесно да разделите на нужните ви дози. Сипете калиевия йодид или смачкайте добре хапчето във водата с лъжичка и разбърквайте до пълно разтваряне. Дръжте разтвора в хладилник, най-добре захлупен, за да не се изпарява лесно (увеличава концентрацията на калиевия йодид в остатъка).

Ако се налага да отмерите калиев йодид на прах, най-добре намерете точна везна за малки тегла. Аптеки които изпълняват микстури и места които ремонтират бижута най-често имат. Заложни къщи, които приемат злато и сребро, често също имат (може да са по-неточни, но отклонението няма да е фатално). Ако не можете да намерите иначе, попитайте в Интернет кой би ви отмерил. (А ако имате с какво да мерите, не се колебайте да помагате на нуждаещи се.)

Ако не можете да отмерите точно малка доза, отмерете най-малкото количество, което можете да отмерите точно. Количества от няколко грама могат да бъдат внимателно доразделени на 2 или 3 равни части върху стъкло с нож; после делете отново до достигане до желаната доза или близо до нея. При делене отведнъж на повече части е по-трудно да ги направите еднакви. Количества от грам и по-малко често е най-добре да бъдат разтворени във вода и тя да бъде делена. (Спринцовки от аптеката – една 10-20 мл и една 1-2 мл – могат да са много полезни. Ако малката е за инсулин, внимавайте с деленията – може да са в инсулинови единици, а не в милилитри: 40 инсулинови единици са 1 милилитър.)

Добра идея е да дадете калиев йодид и на домашните си любимци – и те заслужават предпазване. Най-добре става с нещо, което обичат (калиевият йодид няма мирис, но има горчив вкус). Оптималните дози на единица тегло за бозайници са на практика същите като за хора. За други домашни любимци първо се консултирайте с ветеринарен лекар.

The US Is Spying on the UN Secretary General

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/the-us-is-spying-on-the-un-secretary-general.html

The Washington Post is reporting that the US is spying on the UN Secretary General.

The reports on Guterres appear to contain the secretary general’s personal conversations with aides regarding diplomatic encounters. They indicate that the United States relied on spying powers granted under the Foreign Intelligence Surveillance Act (FISA) to gather the intercepts.

Lots of details about different conversations in the article, which are based on classified documents leaked on Discord by Jack Teixeira.

There will probably a lot of faux outrage at this, but spying on foreign leaders is a perfectly legitimate use of the NSA’s capabilities and authorities. (If the NSA didn’t spy on the UN Secretary General, we should fire it and replace it with a more competent NSA.) It’s the bulk surveillance of whole populations that should outrage us.