Tag Archives: Uncategorized

New AWS Security Blog homepage

Post Syndicated from Anna Brinkmann original https://aws.amazon.com/blogs/security/new-aws-security-blog-homepage/

We’ve launched a new AWS Security Blog homepage! While we currently have no plans to deprecate our existing list-view homepage, we have recently launched a new, security-centered homepage to provide readers with more blog info and easy access to the rest of AWS Security. Please bookmark the new page, and let us know what you think, by adding a comment, below.

Thumbnail view of the new page

The new AWS Security Blog homepage

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

Author

Anna Brinkmann

Anna is a technical editor and writer, and she manages the AWS Security Blog. She enjoys creating helpful content and running short, streamlined meetings. In her free time, you can find her hanging out with her son, reading, and cooking with her air fryer.

Ivy Lin

Ivy Lin

Ivy is a seasoned web production expert. With the nickname “IvyBOT” from previous jobs, she has a passion for transforming raw documents and design comps into web pages with exceptional user experiences. In her spare time, she enjoys sharing information about delicious foods from her mother country of Taiwan with her friends.

Какво се случва с банките в момента, преведено на достъпен език

Post Syndicated from VassilKendov original http://kendov.com/bank-crises/

Пиша тази статия поради многото запитвания на познати как да постъпят в конкретната ситуация с личните си финанси. Не мога да отделя на всички време по телефона, затова ще обясня на разбираем език какво се случва с банките, а по-надолу ще публикувам форма със заявка, за тези които искат да направим конкретна среща и да получат съвет или мнение, съобразени с техните лични финансови намерения.

За да разберем проблема и как ще ни засегне е нужно да познаваме малко от малко основните макроикономически принципи и как работи финансовата система.
Буквално в няколко реда ще обясня на достъпен език, някои от основните пазарни принципи, имащи отношение към сегашната ситуация.

Няй-силният лост за управлението на една икономика е ПАРИЧНАТА МАСА В ОБРАЩЕНИЕ! Тоест парите с които ние боравим. Трябва да знаете, че няма по-силен лост за влияние върху икономиката от този. Когато се развиваш и растеш, печаташ пари за да обслужиш или инициираш този ръст. Когато се появи инфлация от многото пазаруване, вдигаш лихвите за да вкараш парите в банките (на депозити или в ценни книги) и те да не участват в оборота. По този начин също така вдигаш стойността на парите и тушираш инфлацията.

За актуални финансови новини можете да използвате Telegram канала Kendov.com

Когато банките имат излишни пари и достатъчно депозити, с част от тях те купуват ценни книги. Много често това са държавни облигации. Тук ключовия момент е „ЧАСТ ОТ ТЯХ”. Никоя банка няма да допусне портфейла и да се състои само и единствено от ДЦК (държавни ценни книжа). Счита се че ДЦК са безрискови, понеже държавата не може да фалира. Най-малкото може винаги да напечата пари и да покрие задълженията си с цената на инфлация. Затова и инфлацията често се използва за „ликвидиране” на задълженията. Помните голямата инфлация в България през 90-те, когато с доживотните си спестявания си купихте един чифт дънки или обратното – когато с една заплата си погасихте жилищния кредит за следващите 15 години?

Това е един много опростен модел, но трябва да го споменем, за да сме сигурни, че ще разберем важността на случващото се в момента и връзката му с нашите лични финанси.

Какво се случи на практика

От 2008 година насам, централните банки по света пуснаха в обращение БЕЗПРЕЦЕДЕНТНО количество пари. Някой дори заговориха за „хеликоптерни пари”, но сега няма да се отклонявам за да обяснявам какво е това (в Гугъл има достатъчно информация).

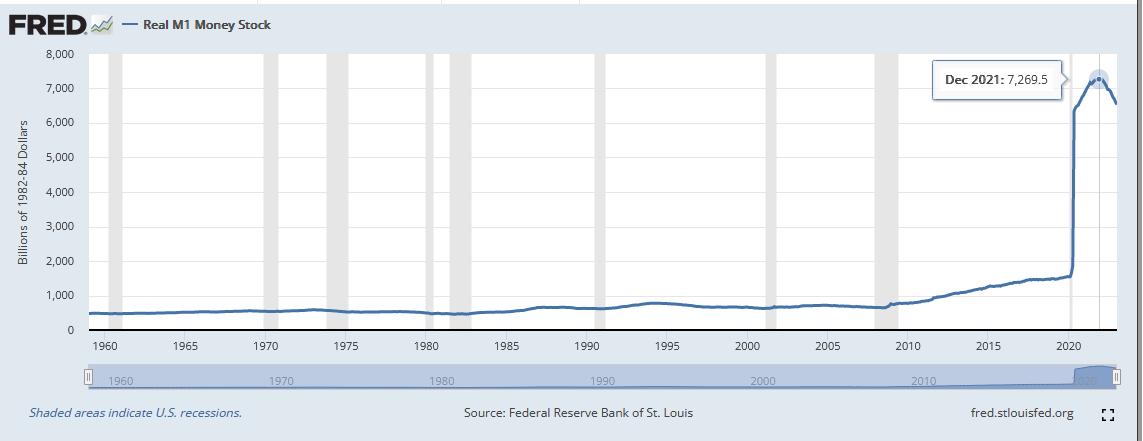
На тази графика Федералния резерв на САЩ са дали как се движи през годините паричната маса в обращение М1 (парите в обращение + кредитните карти+краткосрочните депозити).

От кризата през 2008 виждате, че тази маса нараства. През 2020 има една промяна в начина на отчитане и затова графиката изглежда така. Но като цяло виждате, че преди САЩ да започнат да вдигат лихвите 2021-ва, паричната маса в обращение расте. И то расте добре. Мисля, че няма смисъл да се чудим откъде дойде инфлацията. Само да отбележа, че у нас дойде главно през валутния борд и свързаноста на лева с еврото. Тоест дойде от инфлацията в ЕС, където от 2008 насам също се пуснаха в обращение безпрецедентно количество пари.

През всичките тези годни ливите бяха на исторически ниски нива. EURIBOR-a дори беше отрицателен. Имаше момент в който Германия пусна ДЦК с отрицателна доходност и те бяха изкупени. Тоест като ги купуваш си наясно, че ще си на загуба, но го правиш. Не ме питайте защо, и аз не знам но го правеха.
Като резултат банките се „набълбукаха” с такива дългосрочни и бездоходни ДЦК, но лихвите започнаха да се качват. Както в САЩ, така и в Европа. Този четвъртък ЕЦБ дори вдигна лихвата с още 0.5%.
По този начин купените вече ДЦК започват да губят стойност, защото новите са с 3-4% доходност, а старите с 0-0,5% доходност и то ако ги държиш до падежа. Но пък са част от активите на банката, за съжаление вече с по-ниска цена, защото никой не иска да ги купи. Тоест би ги купил с голяма отстъпка и това вече е загуба за банката.

За  срещa моля използвайте посочената форма.

[contact-form-7]

За вида и качеството на активите има изисквания от страна на централните банки и точно в този момент те поискаха от търговските банки да направят преоценка на активите си, по новите пазарни цени.
Както сами се сещате, това доведе до отчитане на загуби и изисквания тези активи да бъдат заменени с други по-стойностни, за които се изискваше събиране на капитал от фондовите борси.
Това добре, но  вие бихте ли си купили облигации или акции на губещо предприятие, защото след преоценката банките вече бяха на загуба?
Това комбинирано с действията на директорите на банките, които побързаха да продадат акциите си и да изтеглят депозитите си, доведе до така наречения “bank run” – всички теглят авоарите си от тази банка и продават ценните си книги.
Същото става и в Европа, но по традиция  малко закъснение.

Горните са фактите, но интерпретацията им е важна за да сформирате очакванията си.
Доколкото сме в пазарна икономика, фалита би следвало да е нещо нормално. Виждаме обаче, че някои не е приемливо да фалират и затова им помагаме. На други обаче не.
В случая със SVB Bank, Федералния резерв на САЩ взе решение да гарантира депозитите без значение от размера им, защото това са парите на IТ компаниите. Как става това? С пускане на пазара на още пари.
Днес обявиха, че ще бъде спасена и другата закъсала регионална банка – First Republic. Тя щяла да бъде спасена чрез предоставянето на депозити от големите банки, членове на федералния резерв на САЩ.
За Credit Siusse вече знаете, че също ще бъде спасена с помощ от централната банка на Швейцария в размер на 50 млрд франка. Смятайте го като инжектиране на още 50 млрд в обращение. И инфлацията е гарантирана!

Без значение как ще бъдат спасени банките, това ще доведе до увеличение на паричната маса в обращение и то във времена на достатъчно голяма инфлация (около 9.2% средно за ЕС). Но и това не е най-голямият проблем.
Спасявайки големите банки, се случват няколко социални феномена

– Вече не е пазарно да фалираш! Влизаме в комунизма, където предприятията работеха на загуба и накрая държавата покриваше загубата. В сегашния социален строй обаче, загубите в крайна сметка ще се покрият от хората. А какво друго е  инфлацията?
10% инфлация си е близо 10% спад в доходите или 10% данък. Разглеждайте го както ви харесва, но в крайна сметка плащат хората.
– Как очакваме малките да пораснат, ако всеки път спасяваме неефективните големи, за сметка на малките по-прогресивни? Представете си как това влияе на мотивацията на бизнеса. Посланието е – „Колкото и да работиш, голям няма да станеш ако не ти позволим.”

Най-големия проблем от финансова гледна точка е поставянето в подчинение на получилите помощ финансови институции. Разбрате, че няма как просто да им дадат парите, без да има условия. Но всяко условие си е вид подчинение.
Интересно ми е дали и други банки биха „симулирали” фалит за да получат и те помощи.

Наивно е да си мислим, че централните банки не са знаели какво ще се случи, ако вдигнат лихвите и накарат търговските банки да преоценят активите си. Те много добре знаят какъв е портфейла на всяка подотчетна банка и как би повлияло това.

Въпросът е защо го направиха и защо сега?

Лично моето очакване е за още по-висока инфлация и лихви, което да доведе до условия за въвеждане на CBDCs – дигитални пари. Но това е друга тема и за последствията от тяхното въвеждане тепърва ще четете, а аз тепърва ще пиша.
През това време е редно всеки да помисли за спестяванията си и въобще за личните си финанси. Ще помогна с каквото мога, но всеки сам трябва да вземе решение какво да прави в тези условия. В тази ситуация няма после. После е инфлацията!

Ако статията Ви е харесала, помогнете да развием този блог като го споделите на стената си във ФБ. Благодаря Ви предварително.
Можете да се включите в дискусията в Telegram канала Kendov.com

За контакт
[contact-form-7]

The post Какво се случва с банките в момента, преведено на достъпен език appeared first on Kendov.com.

Upcoming Speaking Engagements

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2023/03/upcoming-speaking-engagements-28.html

This is a current list of where and when I am scheduled to speak:

  • I’m speaking on “How to Reclaim Power in the Digital World” at EPFL in Lausanne, Switzerland, on Thursday, March 16, 2023, at 5:30 PM CET.
  • I’ll be discussing my new book A Hacker’s Mind: How the Powerful Bend Society’s Rules at Harvard Science Center in Cambridge, Massachusetts, USA, on Friday, March 31, 2023, at 6:00 PM EDT.
  • I’ll be discussing my book A Hacker’s Mind with Julia Angwin at the Ford Foundation Center for Social Justice in New York City, on Thursday, April 6, 2023, at 6:30 PM EDT. Register here
  • I’m speaking at IT-S Now 2023 in Vienna, Austria, on June 2, 2023, at 8:30 AM CEST.

The list is maintained on this page.

How AI Could Write Our Laws

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2023/03/how-ai-could-write-our-laws.html

Nearly 90% of the multibillion-dollar federal lobbying apparatus in the United States serves corporate interests. In some cases, the objective of that money is obvious. Google pours millions into lobbying on bills related to antitrust regulation. Big energy companies expect action whenever there is a move to end drilling leases for federal lands, in exchange for the tens of millions they contribute to congressional reelection campaigns.

But lobbying strategies are not always so blunt, and the interests involved are not always so obvious. Consider, for example, a 2013 Massachusetts bill that tried to restrict the commercial use of data collected from K-12 students using services accessed via the internet. The bill appealed to many privacy-conscious education advocates, and appropriately so. But behind the justification of protecting students lay a market-altering policy: the bill was introduced at the behest of Microsoft lobbyists, in an effort to exclude Google Docs from classrooms.

What would happen if such legal-but-sneaky strategies for tilting the rules in favor of one group over another become more widespread and effective? We can see hints of an answer in the remarkable pace at which artificial-intelligence tools for everything from writing to graphic design are being developed and improved. And the unavoidable conclusion is that AI will make lobbying more guileful, and perhaps more successful.

It turns out there is a natural opening for this technology: microlegislation.

“Microlegislation” is a term for small pieces of proposed law that cater—sometimes unexpectedly—to narrow interests. Political scientist Amy McKay coined the term. She studied the 564 amendments to the Affordable Care Act (“Obamacare”) considered by the Senate Finance Committee in 2009, as well as the positions of 866 lobbying groups and their campaign contributions. She documented instances where lobbyist comments—on health-care research, vaccine services, and other provisions—were translated directly into microlegislation in the form of amendments. And she found that those groups’ financial contributions to specific senators on the committee increased the amendments’ chances of passing.

Her finding that lobbying works was no surprise. More important, McKay’s work demonstrated that computer models can predict the likely fate of proposed legislative amendments, as well as the paths by which lobbyists can most effectively secure their desired outcomes. And that turns out to be a critical piece of creating an AI lobbyist.

Lobbying has long been part of the give-and-take among human policymakers and advocates working to balance their competing interests. The danger of microlegislation—a danger greatly exacerbated by AI—is that it can be used in a way that makes it difficult to figure out who the legislation truly benefits.

Another word for a strategy like this is a “hack.” Hacks follow the rules of a system but subvert their intent. Hacking is often associated with computer systems, but the concept is also applicable to social systems like financial markets, tax codes, and legislative processes.

While the idea of monied interests incorporating AI assistive technologies into their lobbying remains hypothetical, specific machine-learning technologies exist today that would enable them to do so. We should expect these techniques to get better and their utilization to grow, just as we’ve seen in so many other domains.

Here’s how it might work.

Crafting an AI microlegislator

To make microlegislation, machine-learning systems must be able to uncover the smallest modification that could be made to a bill or existing law that would make the biggest impact on a narrow interest.

There are three basic challenges involved. First, you must create a policy proposal—small suggested changes to legal text—and anticipate whether or not a human reader would recognize the alteration as substantive. This is important; a change that isn’t detectable is more likely to pass without controversy. Second, you need to do an impact assessment to project the implications of that change for the short- or long-range financial interests of companies. Third, you need a lobbying strategizer to identify what levers of power to pull to get the best proposal into law.

Existing AI tools can tackle all three of these.

The first step, the policy proposal, leverages the core function of generative AI. Large language models, the sort that have been used for general-purpose chatbots such as ChatGPT, can easily be adapted to write like a native in different specialized domains after seeing a relatively small number of examples. This process is called fine-tuning. For example, a model “pre-trained” on a large library of generic text samples from books and the internet can be “fine-tuned” to work effectively on medical literature, computer science papers, and product reviews.

Given this flexibility and capacity for adaptation, a large language model could be fine-tuned to produce draft legislative texts, given a data set of previously offered amendments and the bills they were associated with. Training data is available. At the federal level, it’s provided by the US Government Publishing Office, and there are already tools for downloading and interacting with it. Most other jurisdictions provide similar data feeds, and there are even convenient assemblages of that data.

Meanwhile, large language models like the one underlying ChatGPT are routinely used for summarizing long, complex documents (even laws and computer code) to capture the essential points, and they are optimized to match human expectations. This capability could allow an AI assistant to automatically predict how detectable the true effect of a policy insertion may be to a human reader.

Today, it can take a highly paid team of human lobbyists days or weeks to generate and analyze alternative pieces of microlegislation on behalf of a client. With AI assistance, that could be done instantaneously and cheaply. This opens the door to dramatic increases in the scope of this kind of microlegislating, with a potential to scale across any number of bills in any jurisdiction.

Teaching machines to assess impact

Impact assessment is more complicated. There is a rich series of methods for quantifying the predicted outcome of a decision or policy, and then also optimizing the return under that model. This kind of approach goes by different names in different circles—mathematical programming in management science, utility maximization in economics, and rational design in the life sciences.

To train an AI to do this, we would need to specify some way to calculate the benefit to different parties as a result of a policy choice. That could mean estimating the financial return to different companies under a few different scenarios of taxation or regulation. Economists are skilled at building risk models like this, and companies are already required to formulate and disclose regulatory compliance risk factors to investors. Such a mathematical model could translate directly into a reward function, a grading system that could provide feedback for the model used to create policy proposals and direct the process of training it.

The real challenge in impact assessment for generative AI models would be to parse the textual output of a model like ChatGPT in terms that an economic model could readily use. Automating this would require extracting structured financial information from the draft amendment or any legalese surrounding it. This kind of information extraction, too, is an area where AI has a long history; for example, AI systems have been trained to recognize clinical details in doctors’ notes. Early indications are that large language models are fairly good at recognizing financial information in texts such as investor call transcripts. While it remains an open challenge in the field, they may even be capable of writing out multi-step plans based on descriptions in free text.

Machines as strategists

The last piece of the puzzle is a lobbying strategizer to figure out what actions to take to convince lawmakers to adopt the amendment.

Passing legislation requires a keen understanding of the complex interrelated networks of legislative offices, outside groups, executive agencies, and other stakeholders vying to serve their own interests. Each actor in this network has a baseline perspective and different factors that influence that point of view. For example, a legislator may be moved by seeing an allied stakeholder take a firm position, or by a negative news story, or by a campaign contribution.

It turns out that AI developers are very experienced at modeling these kinds of networks. Machine-learning models for network graphs have been built, refined, improved, and iterated by hundreds of researchers working on incredibly diverse problems: lidar scans used to guide self-driving cars, the chemical functions of molecular structures, the capture of motion in actors’ joints for computer graphics, behaviors in social networks, and more.

In the context of AI-assisted lobbying, political actors like legislators and lobbyists are nodes on a graph, just like users in a social network. Relations between them are graph edges, like social connections. Information can be passed along those edges, like messages sent to a friend or campaign contributions made to a member. AI models can use past examples to learn to estimate how that information changes the network. Calculating the likelihood that a campaign contribution of a given size will flip a legislator’s vote on an amendment is one application.

McKay’s work has already shown us that there are significant, predictable relationships between these actions and the outcomes of legislation, and that the work of discovering those can be automated. Others have shown that graphs of neural network models like those described above can be applied to political systems. The full-scale use of these technologies to guide lobbying strategy is theoretical, but plausible.

Put together, these three components could create an automatic system for generating profitable microlegislation. The policy proposal system would create millions, even billions, of possible amendments. The impact assessor would identify the few that promise to be most profitable to the client. And the lobbying strategy tool would produce a blueprint for getting them passed.

What remains is for human lobbyists to walk the floors of the Capitol or state house, and perhaps supply some cash to grease the wheels. These final two aspects of lobbying—access and financing—cannot be supplied by the AI tools we envision. This suggests that lobbying will continue to primarily benefit those who are already influential and wealthy, and AI assistance will amplify their existing advantages.

The transformative benefit that AI offers to lobbyists and their clients is scale. While individual lobbyists tend to focus on the federal level or a single state, with AI assistance they could more easily infiltrate a large number of state-level (or even local-level) law-making bodies and elections. At that level, where the average cost of a seat is measured in the tens of thousands of dollars instead of millions, a single donor can wield a lot of influence—if automation makes it possible to coordinate lobbying across districts.

How to stop them

When it comes to combating the potentially adverse effects of assistive AI, the first response always seems to be to try to detect whether or not content was AI-generated. We could imagine a defensive AI that detects anomalous lobbyist spending associated with amendments that benefit the contributing group. But by then, the damage might already be done.

In general, methods for detecting the work of AI tend not to keep pace with its ability to generate convincing content. And these strategies won’t be implemented by AIs alone. The lobbyists will still be humans who take the results of an AI microlegislator and further refine the computer’s strategies. These hybrid human-AI systems will not be detectable from their output.

But the good news is: the same strategies that have long been used to combat misbehavior by human lobbyists can still be effective when those lobbyists get an AI assist. We don’t need to reinvent our democracy to stave off the worst risks of AI; we just need to more fully implement long-standing ideals.

First, we should reduce the dependence of legislatures on monolithic, multi-thousand-page omnibus bills voted on under deadline. This style of legislating exploded in the 1980s and 1990s and continues through to the most recent federal budget bill. Notwithstanding their legitimate benefits to the political system, omnibus bills present an obvious and proven vehicle for inserting unnoticed provisions that may later surprise the same legislators who approved them.

The issue is not that individual legislators need more time to read and understand each bill (that isn’t realistic or even necessary). It’s that omnibus bills must pass. There is an imperative to pass a federal budget bill, and so the capacity to push back on individual provisions that may seem deleterious (or just impertinent) to any particular group is small. Bills that are too big to fail are ripe for hacking by microlegislation.

Moreover, the incentive for legislators to introduce microlegislation catering to a narrow interest is greater if the threat of exposure is lower. To strengthen the threat of exposure for misbehaving legislative sponsors, bills should focus more tightly on individual substantive areas and, after the introduction of amendments, allow more time before the committee and floor votes. During this time, we should encourage public review and testimony to provide greater oversight.

Second, we should strengthen disclosure requirements on lobbyists, whether they’re entirely human or AI-assisted. State laws regarding lobbying disclosure are a hodgepodge. North Dakota, for example, only requires lobbying reports to be filed annually, so that by the time a disclosure is made, the policy is likely already decided. A lobbying disclosure scorecard created by Open Secrets, a group researching the influence of money in US politics, tracks nine states that do not even require lobbyists to report their compensation.

Ideally, it would be great for the public to see all communication between lobbyists and legislators, whether it takes the form of a proposed amendment or not. Absent that, let’s give the public the benefit of reviewing what lobbyists are lobbying for—and why. Lobbying is traditionally an activity that happens behind closed doors. Right now, many states reinforce that: they actually exempt testimony delivered publicly to a legislature from being reported as lobbying.

In those jurisdictions, if you reveal your position to the public, you’re no longer lobbying. Let’s do the inverse: require lobbyists to reveal their positions on issues. Some jurisdictions already require a statement of position (a ‘yea’ or ‘nay’) from registered lobbyists. And in most (but not all) states, you could make a public records request regarding meetings held with a state legislator and hope to get something substantive back. But we can expect more—lobbyists could be required to proactively publish, within a few days, a brief summary of what they demanded of policymakers during meetings and why they believe it’s in the general interest.

We can’t rely on corporations to be forthcoming and wholly honest about the reasons behind their lobbying positions. But having them on the record about their intentions would at least provide a baseline for accountability.

Finally, consider the role AI assistive technologies may have on lobbying firms themselves and the labor market for lobbyists. Many observers are rightfully concerned about the possibility of AI replacing or devaluing the human labor it automates. If the automating potential of AI ends up commodifying the work of political strategizing and message development, it may indeed put some professionals on K Street out of work.

But don’t expect that to disrupt the careers of the most astronomically compensated lobbyists: former members Congress and other insiders who have passed through the revolving door. There is no shortage of reform ideas for limiting the ability of government officials turned lobbyists to sell access to their colleagues still in government, and they should be adopted and—equally important—maintained and enforced in successive Congresses and administrations.

None of these solutions are really original, specific to the threats posed by AI, or even predominantly focused on microlegislation—and that’s the point. Good governance should and can be robust to threats from a variety of techniques and actors.

But what makes the risks posed by AI especially pressing now is how fast the field is developing. We expect the scale, strategies, and effectiveness of humans engaged in lobbying to evolve over years and decades. Advancements in AI, meanwhile, seem to be making impressive breakthroughs at a much faster pace—and it’s still accelerating.

The legislative process is a constant struggle between parties trying to control the rules of our society as they are updated, rewritten, and expanded at the federal, state, and local levels. Lobbying is an important tool for balancing various interests through our system. If it’s well-regulated, perhaps lobbying can support policymakers in making equitable decisions on behalf of us all.

This article was co-written with Nathan E. Sanders and originally appeared in MIT Technology Review.

NetWire Remote Access Trojan Maker Arrested

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/netwire-remote-access-trojan-maker-arrested.html

From Brian Krebs:

A Croatian national has been arrested for allegedly operating NetWire, a Remote Access Trojan (RAT) marketed on cybercrime forums since 2012 as a stealthy way to spy on infected systems and siphon passwords. The arrest coincided with a seizure of the NetWire sales website by the U.S. Federal Bureau of Investigation (FBI). While the defendant in this case hasn’t yet been named publicly, the NetWire website has been leaking information about the likely true identity and location of its owner for the past 11 years.

The article details the mistakes that led to the person’s address.

Implementing an event-driven serverless story generation application with ChatGPT and DALL-E

Post Syndicated from David Boyne original https://aws.amazon.com/blogs/compute/implementing-an-event-driven-serverless-story-generation-application-with-chatgpt-and-dall-e/

This post demonstrates how to integrate AWS serverless services with artificial intelligence (AI) technologies, ChatGPT, and DALL-E. This full stack event-driven application showcases a method of generating unique bedtime stories for children by using predetermined characters and scenes as a prompt for ChatGPT.

Every night at bedtime, the serverless scheduler triggers the application, initiating an event-driven workflow to create and store new unique AI-generated stories with AI-generated images and supporting audio.

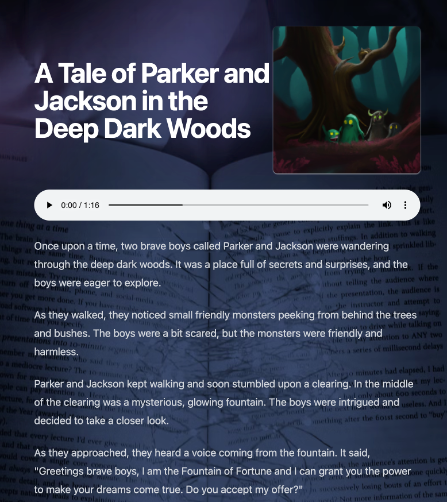
These datasets are used to showcase the story on a custom website built with Next.js hosted with AWS App Runner. After the story is created, a notification is sent to the user containing a URL to view and read the story to the children.

Example notification of a story hosted with Next.js and App Runner

Example notification of a story hosted with Next.js and App Runner

By integrating AWS services with AI technologies, you can now create new and innovative ideas that were previously unimaginable.

The application mentioned in this blog post demonstrates examples of point-to-point messaging with Amazon EventBridge pipes, publish/subscribe patterns with Amazon EventBridge and reacting to change data capture events with DynamoDB Streams.

Understanding the architecture

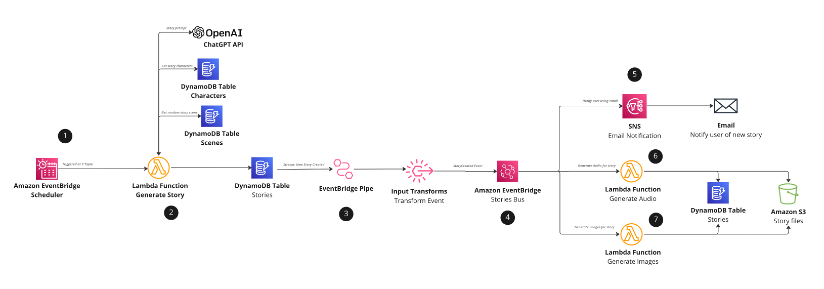
The following image shows the serverless architecture used to generate stories:

Architecture diagram for Serverless bed time story generation with ChatGPT and DALL-E

Architecture diagram for Serverless bed time story generation with ChatGPT and DALL-E

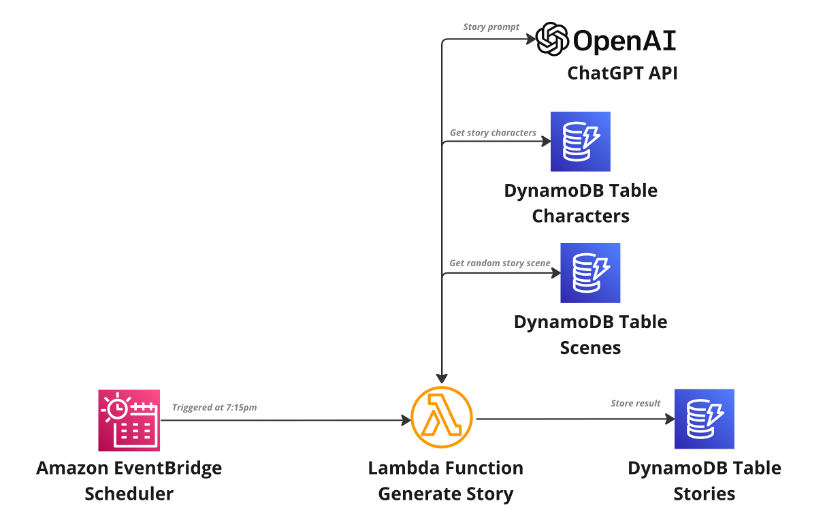
A new children’s story is generated every day at configured time using Amazon EventBridge Scheduler (Step 1). EventBridge Scheduler is a service capable of scaling millions of schedules with over 200 targets and over 6000 API calls. This example application uses EventBridge scheduler to trigger an AWS Lambda function every night at the same time (7:15pm). The Lambda function is triggered to start the generation of the story.

EventBridge scheduler triggers Lambda function every day at 7:15pm (bed time)

EventBridge scheduler triggers Lambda function every day at 7:15pm (bed time)

The “Scenes” and “Characters” Amazon DynamoDB tables contain the characters involved in the story and a scene that is randomly selected during its creation. As a result, ChatGPT receives a unique prompt each time. An example of the prompt may look like this:

“`
Write a title and a rhyming story on 2 main characters called Parker and Jackson. The story needs to be set within the scene haunted woods and be at least 200 words long

“`

After the story is created, it is then saved in the “Stories” DynamoDB table (Step 2).

Scheduler triggering Lambda function to generate the story and store story into DynamoDB

Scheduler triggering Lambda function to generate the story and store story into DynamoDB

Once the story is created this initiates a change data capture event using DynamoDB Streams (Step 3). This event flows through point-to-point messaging with EventBridge pipes and directly into EventBridge. Input transforms are then used to convert the DynamoDB Stream event into a custom EventBridge event, which downstream consumers can comprehend. Adopting this pattern is beneficial as it allows us to separate contracts from the DynamoDB event schema and not having downstream consumers conform to this schema structure, this mapping allows us to remain decoupled from implementation details.

EventBridge Pipes connecting DynamoDB streams directly into EventBridge.

EventBridge Pipes connecting DynamoDB streams directly into EventBridge.

Upon triggering the StoryCreated event in EventBridge, three targets are triggered to carry out several processes (Step 4). Firstly, AI Images are processed, followed by the creation of audio for the story. Finally, the end user is notified of the completed story through Amazon SNS and email subscriptions. This fan-out pattern enables these tasks to be run asynchronously and in parallel, allowing for faster processing times.

EventBridge pub/sub pattern used to start async processing of notifications, audio, and images.

EventBridge pub/sub pattern used to start async processing of notifications, audio, and images.

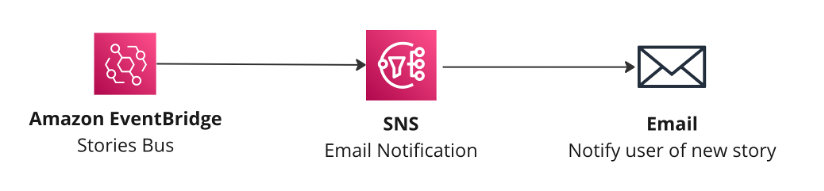
An SNS topic is triggered by the `StoryCreated` event to send an email to the end user using email subscriptions (Step 6). The email consists of a URL with the id of the story that has been created. Clicking on the URL takes the user to the frontend application that is hosted with App Runner.

Using SNS to notify the user of a new story

Using SNS to notify the user of a new story

Example email sent to the user

Example email sent to the user

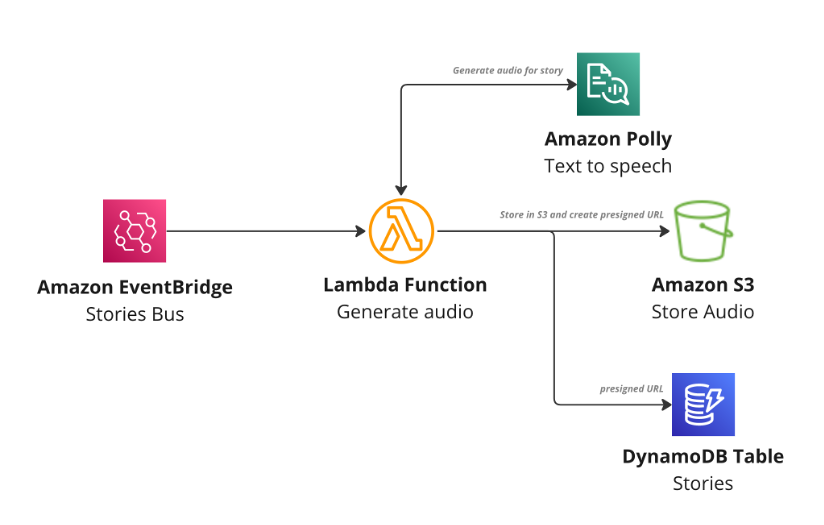
Amazon Polly is used to generate the audio files for the story (Step 6). Upon triggering the `StoryCreated` event, a Lambda function is triggered, and the story description is used and given to Amazon Polly. Amazon Polly then creates an audio file of the story, which is stored in Amazon S3. A presigned URL is generated and saved in DynamoDB against the created story. This allows the frontend application and browser to retrieve the audio file when the user views the page. The presigned URL has a validity of two days, after which it can no longer be accessed or listened to.

Lambda function to generate audio using Amazon Polly, store in S3 and update story with presigned URL

Lambda function to generate audio using Amazon Polly, store in S3 and update story with presigned URL

The `StoryCreated` event also triggers another Lambda function, which uses the OpenAI API to generate an AI image using DALL-E based on the generated story (Step 7). Once the image is generated, the image is downloaded and stored in Amazon S3. Similar to the audio file, the system generates a presigned URL for the image and saves it in DynamoDB against the story. The presigned URL is only valid for two days, after which it becomes inaccessible for download or viewing.

Lambda function to generate images, store in S3 and update story with presigned URL.

Lambda function to generate images, store in S3 and update story with presigned URL.

In the event of a failure in audio or image generation, the frontend application still loads the story, but does not display the missing image or audio at that moment. This ensures that the frontend can continue working and provide value. If you wanted more control and only trigger the user’s notification event once all parallel tasks are complete the aggregator messaging pattern can be considered.

Hosting the frontend Next.js application with AWS App Runner

Next.js is used by the frontend application to render server-side rendered (SSR) pages that can access the stories from the DynamoDB table, which are then hosted with AWS App Runner after being containerized.

Next.js application hosted with App Runner, with permissions into DynamoDB table.

Next.js application hosted with App Runner, with permissions into DynamoDB table.

AWS App Runner enables you to deploy containerized web applications and APIs securely, without needing any prior knowledge of containers or infrastructure. With App Runner, developers can concentrate on their application, while the service handles container startup, running, scaling, and load balancing. After deployment, App Runner provides a secure URL for clients to begin making HTTP requests against.

With App Runner, you have two primary options for deploying your container: source code connections or source images. Using source code connections grants App Runner permission to pull the image file directly from your source code, and with Automatic deployment configured, it can redeploy the application when changes are made. Alternatively, source images provide App Runner with the image’s location in an image registry, and this image is deployed by App Runner.

In this example application, CDK deploys the application using the DockerImageAsset construct with the App Runner construct. Once deployed, App Runner builds and uploads the frontend image to Amazon Elastic Container Registry (ECR) and deploys it. Downstream consumers can access the application using the secure URL provided by App Runner. In this example, the URL is used when the SNS notification is sent to the user when the story is ready to be viewed.

Giving the frontend container permission to DynamoDB table

To grant the Next.js application permission to obtain stories from the Stories DynamoDB table, App Runner instance roles are configured. These roles are optional and can provide the necessary permissions for the container to access AWS services required by the compute service.

If you want to learn more about AWS App Runner, you can explore the free workshop.

Design choices and assumptions

The DynamoDB Time to Live (TTL) feature is ideal for the short-lived nature of daily generated stories. DynamoDB handle the deletion of stories after two days by setting the TTL attribute on each story. Once a story is deleted, it becomes inaccessible through the generated story URLs.

Using Amazon S3 presigned URLs is a method to grant temporary access to a file in S3. This application creates presigned URLs for the audio file and generated images that last for 2 days, after which the URLs for the S3 items become invalid.

Input transforms are used between DynamoDB streams and EventBridge events to decouple the schemas and events consumed by downstream targets. Consuming the events as they are is known as the “conformist” pattern, and couples us to implementation details of DynamoDB streams with downstream EventBridge consumers. This allows the application to remain decoupled from implementation details and remain flexible.

Conclusion

The adoption of artificial intelligence (AI) technology has significantly increased in various industries. ChatGPT, a large language model that can understand and generate human-like responses in natural language, and DALL-E, an image generation system that can create realistic images based on textual descriptions, are examples of such technology. These systems have demonstrated the potential for AI to provide innovative solutions and transform the way we interact with technology.

This blog post explores ways in which you can utilize AWS serverless services with ChatGTP and DALL-E to create a story generation application fronted by a Next.js application hosted with App Runner. EventBridge Scheduler is used to trigger the story creation process then react to change data capture events with DynamoDB streams and EventBridge Pipes, and use Amazon EventBridge to fan out compute tasks to process notifications, images, and audio files.

You can find the documentation and the source code for this application in GitHub.

For more serverless learning resources, visit Serverless Land.

Another Malware with Persistence

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/another-malware-with-persistence.html

Here’s a piece of Chinese malware that infects SonicWall security appliances and survives firmware updates.

On Thursday, security firm Mandiant published a report that said threat actors with a suspected nexus to China were engaged in a campaign to maintain long-term persistence by running malware on unpatched SonicWall SMA appliances. The campaign was notable for the ability of the malware to remain on the devices even after its firmware received new firmware.

“The attackers put significant effort into the stability and persistence of their tooling,” Mandiant researchers Daniel Lee, Stephen Eckels, and Ben Read wrote. “This allows their access to the network to persist through firmware updates and maintain a foothold on the network through the SonicWall Device.”

To achieve this persistence, the malware checks for available firmware upgrades every 10 seconds. When an update becomes available, the malware copies the archived file for backup, unzips it, mounts it, and then copies the entire package of malicious files to it. The malware also adds a backdoor root user to the mounted file. Then, the malware rezips the file so it’s ready for installation.

“The technique is not especially sophisticated, but it does show considerable effort on the part of the attacker to understand the appliance update cycle, then develop and test a method for persistence,” the researchers wrote.

Meet the Newest AWS Heroes – March 2023

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/meet-the-newest-aws-heroes-march-2023/

The AWS Heroes are passionate AWS experts who are dedicated to sharing their in-depth knowledge within the community. They inspire, uplift, and motivate the global AWS community, and today, we’re excited to announce and recognize the newest Heroes in 2023!

Aidan Steele – Melbourne, Australia

Serverless Hero Aidan Steele is a Senior Engineer at Nightvision. He is an avid AWS user, and has been using the first platform and EC2 since 2008. Fifteen years later, EC2 still has a special place in his heart, but his interests are in containers and serverless functions, and blurring the distinction between them wherever possible. He enjoys finding novel uses for AWS services, especially when they have a security or network focus. This is best demonstrated through his open source contributions on GitHub, where he shares interesting use cases via hands-on projects.

Ananda Dwi Rahmawati – Yogyakarta, Indonesia

Container Hero Ananda Dwi Rahmawati is a Sr. Cloud Infrastructure Engineer, specializing in system integration between cloud infrastructure, CI/CD workflows, and application modernization. She implements solutions using powerful services provided by AWS, such as Amazon Elastic Kubernetes Service (EKS), combined with open source tools to achieve the goal of creating reliable, highly available, and scalable systems. She is a regular technical speaker who delivers presentations using real-world case studies at several local community meetups and conferences, such as Kubernetes and OpenInfra Days Indonesia, AWS Community Day Indonesia, AWS Summit ASEAN, and many more.

Wendy Wong – Sydney, Australia

Data Hero Wendy Wong is a Business Performance Analyst at Service NSW, building data pipelines with AWS Analytics and agile projects in AI. As a teacher at heart, she enjoys sharing her passion as a Data Analytics Lead Instructor for General Assembly Sydney, writing technical blogs on dev.to. She is both an active speaker for AWS analytics and an advocate of diversity and inclusion, presenting at a number of events: AWS User Group Malaysia, Women Who Code, AWS Summit Australia 2022, AWS BuildHers, AWS Innovate Modern Applications, and many more.

Learn More

If you’d like to learn more about the new Heroes or connect with a Hero near you, please visit the AWS Heroes website or browse the AWS Heroes Content Library.

Taylor

BlackLotus Malware Hijacks Windows Secure Boot Process

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/blacklotus-malware-hijacks-windows-secure-boot-process.html

Researchers have discovered malware that “can hijack a computer’s boot process even when Secure Boot and other advanced protections are enabled and running on fully updated versions of Windows.”

Dubbed BlackLotus, the malware is what’s known as a UEFI bootkit. These sophisticated pieces of malware target the UEFI—short for Unified Extensible Firmware Interface—the low-level and complex chain of firmware responsible for booting up virtually every modern computer. As the mechanism that bridges a PC’s device firmware with its operating system, the UEFI is an OS in its own right. It’s located in an SPI-connected flash storage chip soldered onto the computer motherboard, making it difficult to inspect or patch. Previously discovered bootkits such as CosmicStrand, MosaicRegressor, and MoonBounce work by targeting the UEFI firmware stored in the flash storage chip. Others, including BlackLotus, target the software stored in the EFI system partition.

Because the UEFI is the first thing to run when a computer is turned on, it influences the OS, security apps, and all other software that follows. These traits make the UEFI the perfect place to launch malware. When successful, UEFI bootkits disable OS security mechanisms and ensure that a computer remains infected with stealthy malware that runs at the kernel mode or user mode, even after the operating system is reinstalled or a hard drive is replaced.

ESET has an analysis:

The number of UEFI vulnerabilities discovered in recent years and the failures in patching them or revoking vulnerable binaries within a reasonable time window hasn’t gone unnoticed by threat actors. As a result, the first publicly known UEFI bootkit bypassing the essential platform security feature—UEFI Secure Boot—is now a reality. In this blogpost we present the first public analysis of this UEFI bootkit, which is capable of running on even fully-up-to-date Windows 11 systems with UEFI Secure Boot enabled. Functionality of the bootkit and its individual features leads us to believe that we are dealing with a bootkit known as BlackLotus, the UEFI bootkit being sold on hacking forums for $5,000 since at least October 2022.

[…]

  • It’s capable of running on the latest, fully patched Windows 11 systems with UEFI Secure Boot enabled.
  • It exploits a more than one year old vulnerability (CVE-2022-21894) to bypass UEFI Secure Boot and set up persistence for the bootkit. This is the first publicly known, in-the-wild abuse of this vulnerability.
  • Although the vulnerability was fixed in Microsoft’s January 2022 update, its exploitation is still possible as the affected, validly signed binaries have still not been added to the UEFI revocation list. BlackLotus takes advantage of this, bringing its own copies of legitimate—but vulnerable—binaries to the system in order to exploit the vulnerability.
  • It’s capable of disabling OS security mechanisms such as BitLocker, HVCI, and Windows Defender.
  • Once installed, the bootkit’s main goal is to deploy a kernel driver (which, among other things, protects the bootkit from removal), and an HTTP downloader responsible for communication with the C&C and capable of loading additional user-mode or kernel-mode payloads.

This is impressive stuff.

Prompt Injection Attacks on Large Language Models

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/prompt-injection-attacks-on-large-language-models.html

This is a good survey on prompt injection attacks on large language models (like ChatGPT).

Abstract: We are currently witnessing dramatic advances in the capabilities of Large Language Models (LLMs). They are already being adopted in practice and integrated into many systems, including integrated development environments (IDEs) and search engines. The functionalities of current LLMs can be modulated via natural language prompts, while their exact internal functionality remains implicit and unassessable. This property, which makes them adaptable to even unseen tasks, might also make them susceptible to targeted adversarial prompting. Recently, several ways to misalign LLMs using Prompt Injection (PI) attacks have been introduced. In such attacks, an adversary can prompt the LLM to produce malicious content or override the original instructions and the employed filtering schemes. Recent work showed that these attacks are hard to mitigate, as state-of-the-art LLMs are instruction-following. So far, these attacks assumed that the adversary is directly prompting the LLM.

In this work, we show that augmenting LLMs with retrieval and API calling capabilities (so-called Application-Integrated LLMs) induces a whole new set of attack vectors. These LLMs might process poisoned content retrieved from the Web that contains malicious prompts pre-injected and selected by adversaries. We demonstrate that an attacker can indirectly perform such PI attacks. Based on this key insight, we systematically analyze the resulting threat landscape of Application-Integrated LLMs and discuss a variety of new attack vectors. To demonstrate the practical viability of our attacks, we implemented specific demonstrations of the proposed attacks within synthetic applications. In summary, our work calls for an urgent evaluation of current mitigation techniques and an investigation of whether new techniques are needed to defend LLMs against these threats.

New National Cybersecurity Strategy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/new-national-cybersecurity-strategy.html

Last week, the Biden administration released a new National Cybersecurity Strategy (summary here). There is lots of good commentary out there. It’s basically a smart strategy, but the hard parts are always the implementation details. It’s one thing to say that we need to secure our cloud infrastructure, and another to detail what the means technically, who pays for it, and who verifies that it’s been done.

One of the provisions getting the most attention is a move to shift liability to software vendors, something I’ve been advocating for since at least 2003.

Slashdot thread.

Friday Squid Blogging: We’re Almost at Flying Squid Drones

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/friday-squid-blogging-were-almost-at-flying-squid-drones.html

Researchers are prototyping multi-segment shapeshifter drones, which are “the precursors to flying squid-bots.”

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Nick Weaver on Regulating Cryptocurrency

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/nick-weaver-on-regulating-cryptocurrency.html

Nicholas Weaver wrote an excellent paper on the problems of cryptocurrencies and the need to regulate the space—with all existing regulations. His conclusion:

Regulators, especially regulators in the United States, often fear accusations of stifling innovation. As such, the cryptocurrency space has grown over the past decade with very little regulatory oversight.

But fortunately for regulators, there is no actual innovation to stifle. Cryptocurrencies cannot revolutionize payments or finance, as the basic nature of all cryptocurrencies render them fundamentally unsuitable to revolutionize our financial system—which, by the way, already has decades of successful experience with digital payments and electronic money. The supposedly “decentralized” and “trustless” cryptocurrency systems, both technically and socially, fail to provide meaningful benefits to society—and indeed, necessarily also fail in their foundational claims of decentralization and trustlessness.

When regulating cryptocurrencies, the best starting point is history. Regulating various tokens is best done through the existing securities law framework, an area where the US has a near century of well-established law. It starts with regulating the issuance of new cryptocurrency tokens and related securities. This should substantially reduce the number of fraudulent offerings.

Similarly, active regulation of the cryptocurrency exchanges should offer substantial benefits, including eliminating significant consumer risk, blocking key money-laundering channels, and overall producing a far more regulated and far less manipulated market.

Finally, the stablecoins need basic regulation as money transmitters. Unless action is taken they risk becoming substantial conduits for money laundering, but requiring them to treat all users as customers should prevent this risk from developing further.

Read the whole thing.

Dumb Password Rules

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/03/dumb-password-rules.html

Examples of dumb password rules.

There are some pretty bad disasters out there.

My worst experiences are with sites that have artificial complexity requirements that cause my personal password-generation systems to fail. Some of the systems on the list are even worse: when they fail they don’t tell you why, so you just have to guess until you get it right.

Content Repository for Unstructured Data with Multilingual Semantic Search: Part 1

Post Syndicated from Patrik Nagel original https://aws.amazon.com/blogs/architecture/content-repository-for-unstructured-data-with-multilingual-semantic-search-part-1/

Unstructured data can make up to 80 percent of data in the day-to-day business of financial organizations. For example, these organizations typically store and read PDFs and images for claim processing, underwriting, and know your customer (KYC). Organizations need to make this ingested data accessible and searchable across different entities while logically separating data access according to role requirements.

In this two-part series, we use AWS services to build an end-to-end content repository for storing and processing unstructured data with the following features:

  • Dynamic access control-based logic over unstructured data
  • Multilingual semantic search capabilities

In part 1, we build the architectural foundation for the content repository, including the resource access control logic and a web UI to upload and list documents.

Solution overview

The content repository includes four building blocks:

Frontend and interaction: For this function, we use AWS Amplify, which is a set of purpose-built tools and features to help frontend web and mobile developers quickly build full-stack applications on AWS. The React application uses the AWS Amplify authentication feature to quickly set up a complete authentication flow integrated into Amazon Cognito. Amplify also hosts the frontend application.

Authentication and authorization: Implementing dynamic resource access control with a combination of roles and attributes is fundamental to your content repository security. Amazon Cognito provides a managed, scalable user directory, user sign-up and sign-in flows, and federation capabilities through third-party identity providers. We use Amazon Cognito user pools as the source of user identity for the content repository. You can work with user pool groups to represent different types of user collection, and you can manage their permissions using a group-associated AWS Identity and Access Management (IAM) role.

Users authenticate against the Amazon Cognito user pool. The web app will exchange the user pool tokens for AWS credentials through an Amazon Cognito identity pool in the content repository. You can complement the IAM role-based authorization model by mapping your relevant attributes to principal tags that will be evaluated as part of IAM permission policies. This allows a dynamic and flexible authorization strategy. For use cases that need federation with third-party identity providers, you can base your user collection on existing user group attributes, such as Active Directory group membership.

Backend and business logic: Authenticated users are redirected to the Amazon API Gateway. API Gateway provides managed publishing for application programming interfaces (APIs) that act as the repository’s “front door.” API Gateway also interacts with the repository’s backend through RESTful APIs. This makes the business logic of the content repository extensible for future use cases, such as transcription and translation. We use AWS Lambda as a serverless, event-driven compute service to run specific business logic code, such as uploading a document to the content repository.

Content storage: Amazon Simple Storage Service (Amazon S3) provides virtually unlimited scalability and high durability. With Amazon S3, you can cost-effectively store unstructured documents in their native formats and make it accessible in a secure and scalable way. Enriching the uploaded documents with tags simplifies data governance with fine-grained access control.

Technical architecture

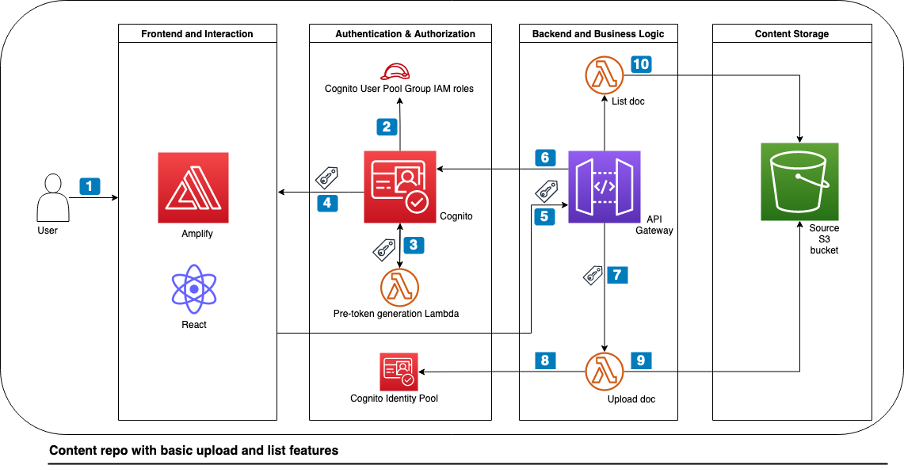
The technical architecture of the content repository with these four components can be found in Figure 1.

Technical architecture of the content repository

Figure 1. Technical architecture of the content repository

Let’s explore the architecture step by step.

  1. The frontend uses the Amplify JS library to add the authentication UI component to your React app, allowing authenticated users to sign in.
  2. Once the user provides their sign-in credentials, they are redirected to Amazon Cognito user pools to be authenticated.
  3. Once the authentication is successful, Amazon Cognito invokes a pre-token generation Lambda function. This function customizes the identity (ID) token with a new claim called department. This new claim is the Amazon Cognito group name from the cognito:preferred_role claim.
  4. Amazon Cognito returns the identity, access, and refresh token in JSON format to the frontend.
  5. The Amplify client library stores the tokens and handles refreshes using the refresh token while the React frontend application calls the API Gateway with the ID token. Note: Usually, you would use the access token to grant access to authorized resources. For this architecture, we use the ID token because we have enriched it with the custom claim during step 3.
  6. API Gateway uses its native integration with Amazon Cognito and validates the ID token’s signature and expiration using Amazon Cognito user pool authorizer. For more complex authorization scenarios, you can use API Gateway Lambda authorizer with the AWS JSON Web Token (JWT) Verify library for verifying JWTs signed by Amazon Cognito.
  7. After successful validation, API Gateway passes the ID token to the backend Lambda function, which can verify and authorize upon it for access control.
  8. Upon document upload action, the backend Lambda function calls the Amazon Cognito identity pool to exchange the ID token for the temporary AWS credentials associated with the cognito:preferred_role claim.
  9. The document upload Lambda function returns a pre-signed URL with the custom department claim in the Amazon S3 path prefix as well as the object tag. The Amazon S3 pre-signed URL is used for the document upload from the frontend application directly to Amazon S3.
  10. Upon document list action, similar to step 8, the backend Lambda function exchanges the ID token for the temporary AWS credentials. The Lambda function returns only the documents based on the user’s preferred group and associated custom department claim.

Prerequisites

You must have the following prerequisites for this solution:

Walkthrough

Setup

The following steps will deploy two AWS CDK stacks into your AWS account:

  • content-repo-stack (blog-content-repo-stack.ts) creates the environment detailed in Figure 1.
  • demo-data-stack (userpool-demo-data-stack.ts) deploys sample users, groups, and role mappings.

To continue setup, use the following commands:

  1. Clone the project git repository:
    git clone https://github.com/aws-samples/content-repository-with-dynamic-access-control content-repository
  2. Install the necessary dependencies:
    cd content-repository/backend-cdk
    npm install
    
  3. Configure environment variables:
    export CDK_DEFAULT_ACCOUNT=$(aws sts get-caller-identity --query 'Account' --output text)
    export CDK_DEFAULT_REGION=$(aws configure get region)
    
  4. Bootstrap your account for AWS CDK usage:
    cdk bootstrap aws://$CDK_DEFAULT_ACCOUNT/$CDK_DEFAULT_REGION
  5. Deploy the code to your AWS account:
    cdk deploy --all

Using the repository

Once you deploy the CDK stacks in your AWS account, follow these steps:

1. Access the frontend application:

a. Copy the amplifyHostedAppUrl value shown in the AWS CDK output from the content-repo-stack.

b. Use the URL with your web browser to access the frontend application.

c. A temporary page displays until the automated build and deployment of the React application completes after 4-5 minutes.

2. Application sign-in and role-based access control (RBAC):

a. The React webpage prompts you to sign in and then change the temporary password.

b. The content repository provides two demo users with credentials as part of the demo-data-stack in the AWS CDK output. In this walkthrough, we use the sales-user user, which belongs to the sales department group to validate RBAC.

3. Upload a document to the content repository:

a. Authenticate as sales-user.

b. Select upload to upload your first document to the content repository.

c. The repository provides sample documents in the assets sub-folder.

4. List your uploaded document:

a. Select list to show the uploaded sales content.

b. To verify the dynamic access control, repeat steps 2 and 3 for the marketing-user user, which belongs to the marketing department group.

c. Sign-in to the AWS Management Console and navigate to the Amazon S3 bucket with the prefix content-repo-stack-s3sourcebucket to confirm that all the uploaded content exists.

Implementation notes

Frontend deployment and cross-origin access

The content-repo-stack contains an AwsCustomResource construct. This construct uses the Amplify API to start the release job of the Amplify hosted frontend application. The preBuild step of the Amplify application build specification dynamically configures its backend for the Amazon Cognito-based authentication. The required Amazon Cognito configuration parameters are retrieved from the AWS Systems Manager Parameter Store during build time. Similarly, the Amplify application postBuild step updates the Amazon S3 cross-origin resource sharing (CORS) rule for the Amazon S3 bucket to only allow cross-origin access from the Amplify-hosted URL of the frontend application.

Application sign-in and access control

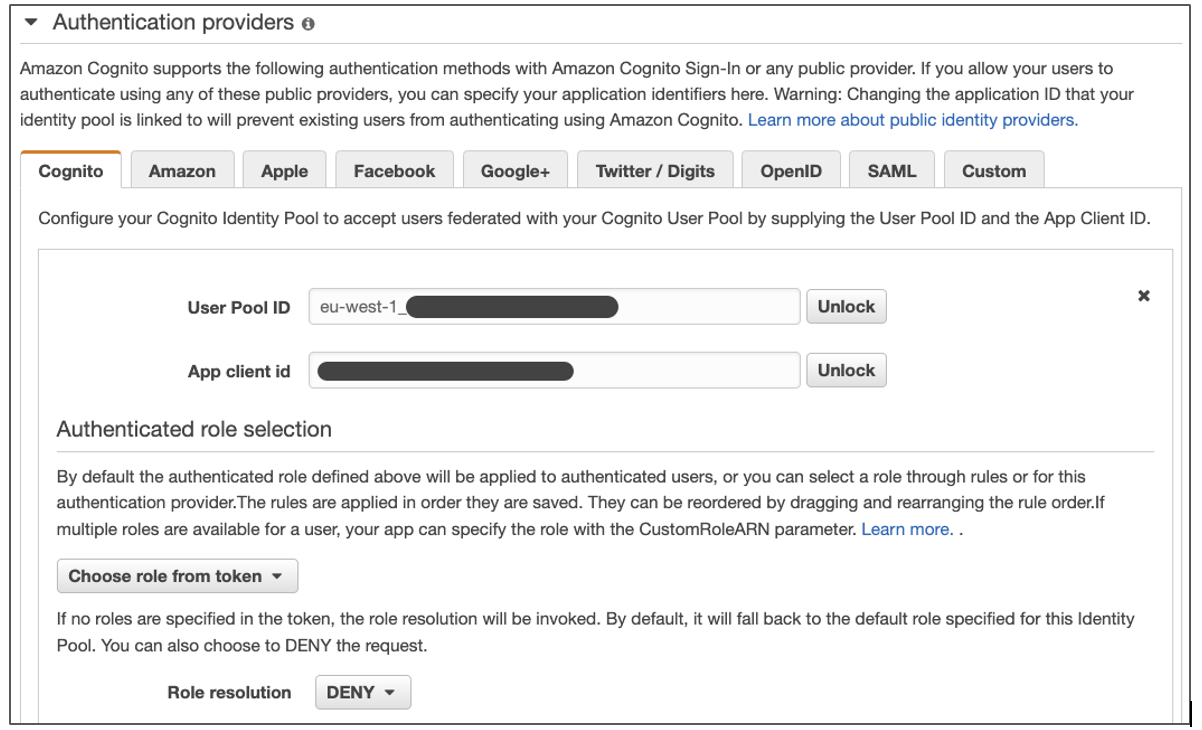
The Amazon Cognito identity pool configuration is set to Choose role from token for authenticated users, as in Figure 2. This setup permits authenticated users to pass the roles in the ID token that the Amazon Cognito user pool assigned. Backend Lambda functions use the roles that appear in the cognito:roles and cognito:preferred_role claims in the ID token for RBAC.

Amazon Cognito identity pool configuration – using tokens to assign roles to authenticated users

Figure 2. Amazon Cognito identity pool configuration – using tokens to assign roles to authenticated users

In the attributes for access control section, we configured a custom mapping from the augmented department token claim to a tag key, as in Figure 3. The backend logic uses the tag key to match the PrincipalTag condition in IAM policies to control access to AWS resources.

Amazon Cognito identity pool configuration – custom mapping from claim names to tag keys

Figure 3. Amazon Cognito identity pool configuration – custom mapping from claim names to tag keys

Document upload

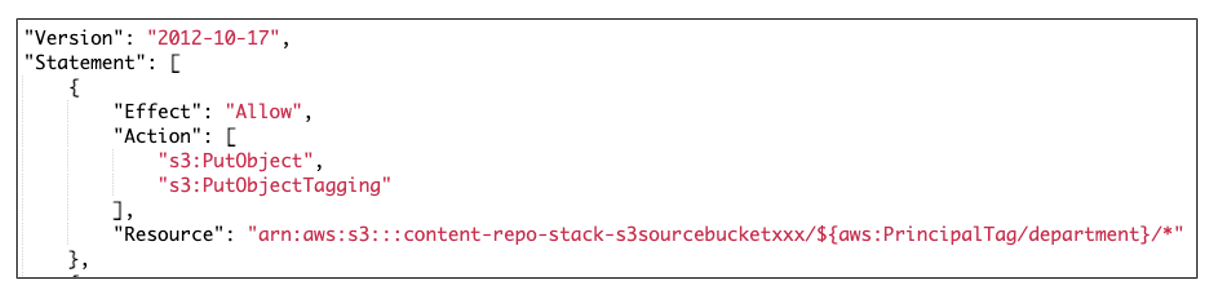
The presigned_url.py Lambda function generates a pre-signed Amazon S3 URL using the department token claim as the key. This function automatically organizes the uploaded document into a logical structure in the Amazon S3 source bucket. Accordingly, the cognito:preferred_role used for the Amazon S3 client credentials in the Lambda function has a permission policy using the PrincipalTag department to dynamically limit access to the Amazon S3 key, as in Figure 4.

Permission policy using PrincipalTag to upload documents to Amazon S3

Figure 4. Permission policy using PrincipalTag to upload documents to Amazon S3

Document listing

The list functionality only shows the uploaded content belonging to the preferred group of authenticated Amazon Cognito user pool user. To only list the files that a specific user (for example, sales-user) has access to, use the PrincipalTag s3:prefix condition, as in Figure 5.

Permission policy using s3:prefix condition with session tags to list documents

Figure 5. Permission policy using s3:prefix condition with session tags to list documents

Cleanup

In the backend-cdk subdirectory, delete the deployed resources:

cdk destroy --all

Conclusion

In this blog, we demonstrated how to build a content repository with an easy-to-use web application for unstructured data that ingests documents while maintaining dynamic access control for users within departments. These steps provide a foundation to build your own content repository to store and process documents. As next steps, based on your organization’s security requirements, you can implement more complex access control use cases by balancing IAM role and principal tags. For example, you can use Amazon Cognito user pool custom attributes for additional dimensions such as document “clearance” with optional modification in the pre-token generation Lambda.

In the next part of this blog series, we will enrich the content repository with multi-lingual semantic search features while maintaining the access control fundamentals we’ve already implemented. For additional information on how you can build a solution to search for information across multiple scanned documents, PDFs, and images with compliance capabilities, please refer our Document Understanding Solution from AWS Solutions Library.

Proactive Insights with Amazon DevOps Guru for RDS

Post Syndicated from Kishore Dhamodaran original https://aws.amazon.com/blogs/devops/proactive-insights-with-amazon-devops-guru-for-rds/

Today, we are pleased to announce a new Amazon DevOps Guru for RDS capability: Proactive Insights. DevOps Guru for RDS is a fully-managed service powered by machine learning (ML), that uses the data collected by RDS Performance Insights to detect and alert customers of anomalous behaviors within Amazon Aurora databases. Since its release, DevOps Guru for RDS has empowered customers with information to quickly react to performance problems and to take corrective actions. Now, Proactive Insights adds recommendations related to operational issues that may prevent potential issues in the future.

Proactive Insights requires no additional set up for customers already using DevOps Guru for RDS, for both Amazon Aurora MySQL-Compatible Edition and Amazon Aurora PostgreSQL-Compatible Edition.

The following are example use cases of operational issues available for Proactive Insights today, with more insights coming over time:

  • Long InnoDB History for Aurora MySQL-Compatible engines – Triggered when the InnoDB history list length becomes very large.
  • Temporary tables created on disk for Aurora MySQL-Compatible engines – Triggered when the ratio of temporary tables created versus all temporary tables breaches a threshold.
  • Idle In Transaction for Aurora PostgreSQL-Compatible engines – Triggered when sessions connected to the database are not performing active work, but can keep database resources blocked.

To get started, navigate to the Amazon DevOps Guru Dashboard where you can see a summary of your system’s overall health, including ongoing proactive insights. In the following screen capture, the number three indicates that there are three ongoing proactive insights. Click on that number to see the listing of the corresponding Proactive Insights, which may include RDS or other Proactive Insights supported by Amazon DevOps Guru.

Amazon DevOps Guru Dashboard where you can see a summary of your system’s overall health, including ongoing proactive insights

Figure 1. Amazon DevOps Guru Dashboard where you can see a summary of your system’s overall health, including ongoing proactive insights.

Ongoing problems (including reactive and proactive insights) are also highlighted against your database instance on the Database list page in the Amazon RDS console.

Proactive and Reactive Insights are highlighted against your database instance on the Database list page in the Amazon RDS console

Figure 2. Proactive and Reactive Insights are highlighted against your database instance on the Database list page in the Amazon RDS console.

In the following sections, we will dive deep on these use cases of DevOps Guru for RDS Proactive Insights.

Long InnoDB History for Aurora MySQL-Compatible engines

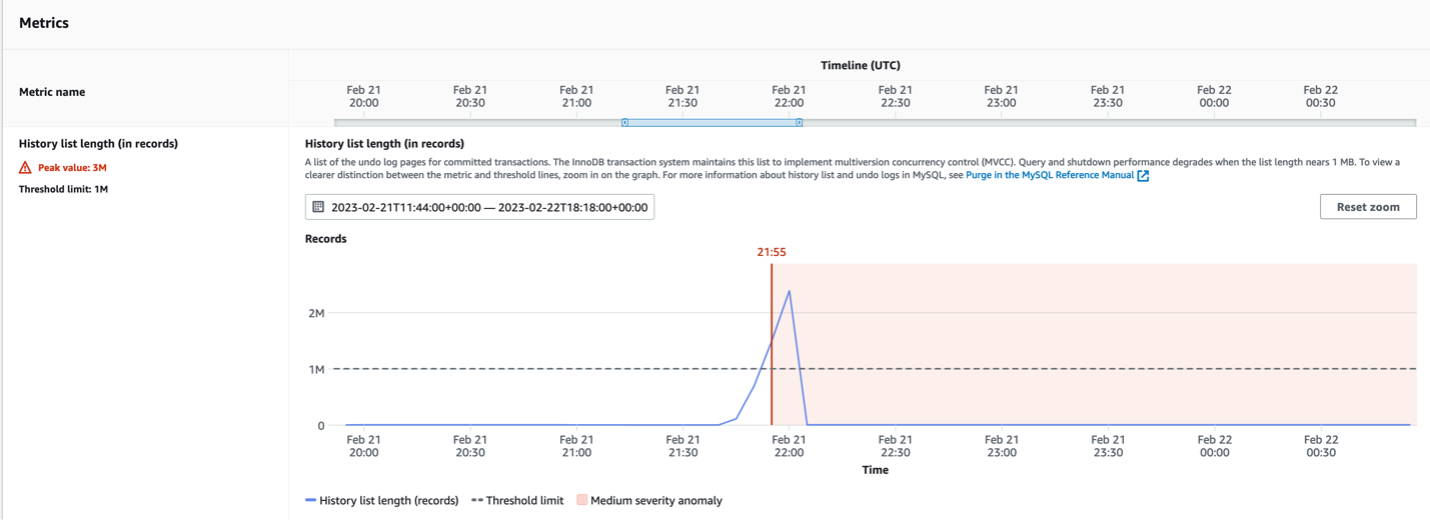
The InnoDB history list is a global list of the undo logs for committed transactions. MySQL uses the history list to purge records and log pages when transactions no longer require the history.  If the InnoDB history list length grows too large, indicating a large number of old row versions, queries and even the database shutdown process can become slower.

DevOps Guru for RDS now detects when the history list length exceeds 1 million records and alerts users to close (either by commit or by rollback) any unnecessary long-running transactions before triggering database changes that involve a shutdown (this includes reboots and database version upgrades).

From the DevOps Guru console, navigate to Insights, choose Proactive, then choose “RDS InnoDB History List Length Anomalous” Proactive Insight with an ongoing status. You will notice that Proactive Insights provides an “Insight overview”, “Metrics” and “Recommendations”.

Insight overview provides you basic information on this insight. In our case, the history list for row changes increased significantly, which affects query and shutdown performance.

Long InnoDB History for Aurora MySQL-Compatible engines Insight overview

Figure 3. Long InnoDB History for Aurora MySQL-Compatible engines Insight overview.

The Metrics panel gives you a graphical representation of the history list length and the timeline, allowing you to correlate it with any anomalous application activity that may have occurred during this window.

Long InnoDB History for Aurora MySQL-Compatible engines Metrics panel

Figure 4. Long InnoDB History for Aurora MySQL-Compatible engines Metrics panel.

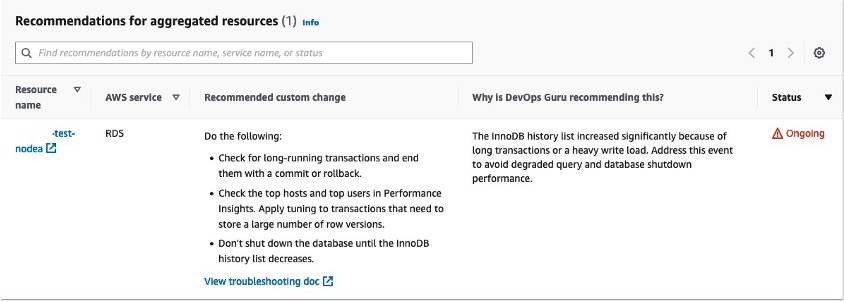
The Recommendations section suggests actions that you can take to mitigate this issue before it leads to a bigger problem. You will also notice the rationale behind the recommendation under the “Why is DevOps Guru recommending this?” column.

The Recommendations section suggests actions that you can take to mitigate this issue before it leads to a bigger problem

Figure 5. The Recommendations section suggests actions that you can take to mitigate this issue before it leads to a bigger problem.

Temporary tables created on disk for Aurora MySQL-Compatible engines

Sometimes it is necessary for the MySQL database to create an internal temporary table while processing a query. An internal temporary table can be held in memory and processed by the TempTable or MEMORY storage engine, or stored on disk by the InnoDB storage engine. An increase of temporary tables created on disk instead of in memory can impact the database performance.

DevOps Guru for RDS now monitors the rate at which the database creates temporary tables and the percentage of those temporary tables that use disk. When these values cross recommended levels over a given period of time, DevOps Guru for RDS creates an insight exposing this situation before it becomes critical.

From the DevOps Guru console, navigate to Insights, choose Proactive, then choose “RDS Temporary Tables On Disk AnomalousProactive Insight with an ongoing status. You will notice this Proactive Insight provides an “Insight overview”, “Metrics” and “Recommendations”.

Insight overview provides you basic information on this insight. In our case, more than 58% of the total temporary tables created per second were using disk, with a sustained rate of two temporary tables on disk created every second, which indicates that query performance is degrading.

Temporary tables created on disk insight overview

Figure 6. Temporary tables created on disk insight overview.

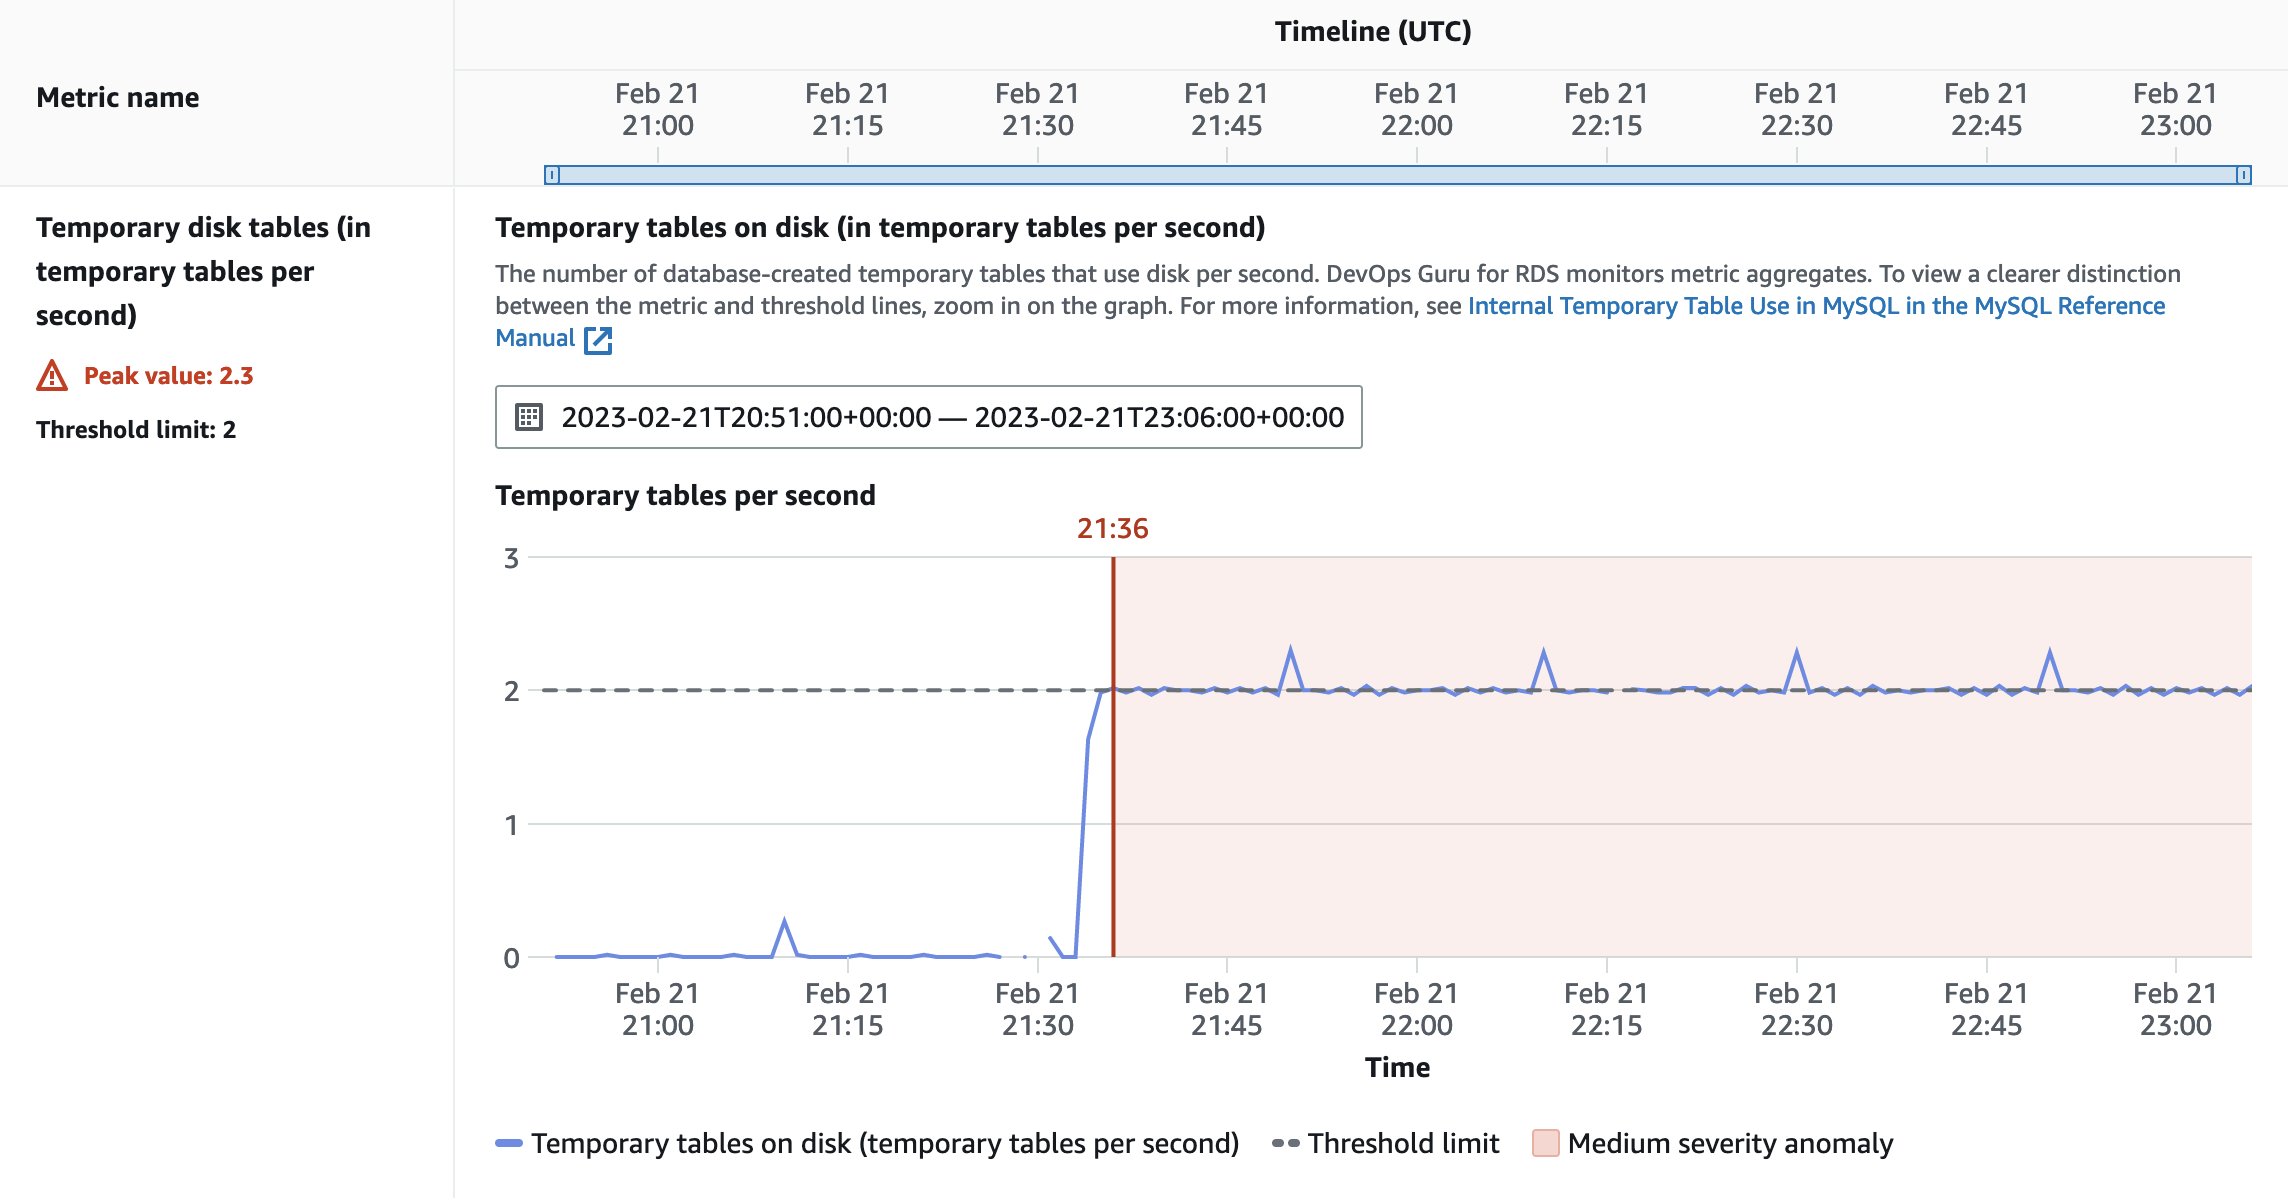
The Metrics panel shows you a graphical representation of the information specific for this insight. You will be presented with the evolution of the amount of temporary tables created on disk per second, the percentage of temporary tables on disk (out of the total number of database-created temporary tables), and of the overall rate at which the temporary tables are created (per second).

Temporary tables created on disk evolution of the amount of temporary tables created on disk per second

Figure 7. Temporary tables created on disk – evolution of the amount of temporary tables created on disk per second.

Temporary tables created on disk the percentage of temporary tables on disk (out of the total number of database-created temporary tables)

Figure 8. Temporary tables created on disk – the percentage of temporary tables on disk (out of the total number of database-created temporary tables).

Temporary tables created on disk overall rate at which the temporary tables are created (per second)

Figure 9. Temporary tables created on disk – overall rate at which the temporary tables are created (per second).

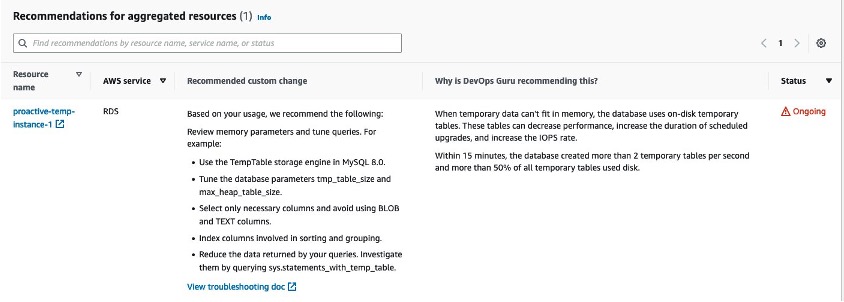
The Recommendations section suggests actions to avoid this situation when possible, such as not using BLOB and TEXT data types, tuning tmp_table_size and max_heap_table_size database parameters, data set reduction, columns indexing and more.

Temporary tables created on disk actions to avoid this situation when possible, such as not using BLOB and TEXT data types, tuning tmp_table_size and max_heap_table_size database parameters, data set reduction, columns indexing and more

Figure 10. Temporary tables created on disk – actions to avoid this situation when possible, such as not using BLOB and TEXT data types, tuning tmp_table_size and max_heap_table_size database parameters, data set reduction, columns indexing and more.

Additional explanations on this use case can be found by clicking on the “View troubleshooting doc” link.

Idle In Transaction for Aurora PostgreSQL-Compatible engines

A connection that has been idle in transaction  for too long can impact performance by holding locks, blocking other queries, or by preventing VACUUM (including autovacuum) from cleaning up dead rows.
PostgreSQL database requires periodic maintenance, which is known as vacuuming. Autovacuum in PostgreSQL automates the execution of VACUUM and ANALYZE commands. This process gathers the table statistics and deletes the dead rows. When vacuuming does not occur, this negatively impacts the database performance. It leads to an increase in table and index bloat (the disk space that was used by a table or index and is available for reuse by the database but has not been reclaimed), leads to stale statistics and can even end in transaction wraparound (when the number of unique transaction ids reaches its maximum of about two billion).

DevOps Guru for RDS monitors the time spent by sessions in an Aurora PostgreSQL database in idle in transaction state and raises initially a warning notification, followed by an alarm notification if the idle in transaction state continues (the current thresholds are 1800 seconds for the warning and 3600 seconds for the alarm).

From the DevOps Guru console, navigate to Insights, choose Proactive, then choose “RDS Idle In Transaction Max Time AnomalousProactive Insight with an ongoing status. You will notice this Proactive Insights provides an “Insight overview”, “Metrics” and “Recommendations”.

In our case, a connection has been in “idle in transaction” state for more than 1800 seconds, which could impact the database performance.

A connection has been in “idle in transaction” state for more than 1800 seconds, which could impact the database performance

Figure 11. A connection has been in “idle in transaction” state for more than 1800 seconds, which could impact the database performance.

The Metrics panel shows you a graphical representation of when the long-running “idle in transaction” connections started.

The Metrics panel shows you a graphical representation of when the long-running “idle in transaction” connections started

Figure 12. The Metrics panel shows you a graphical representation of when the long-running “idle in transaction” connections started.

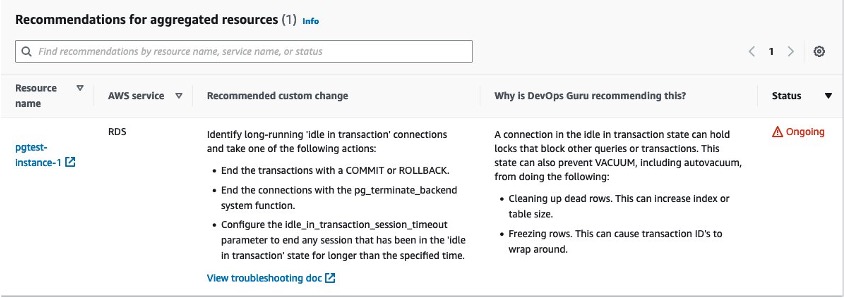
As with the other insights, recommended actions are listed and a troubleshooting doc is linked for even more details on this use case.

Recommended actions are listed and a troubleshooting doc is linked for even more details on this use case

Figure 13. Recommended actions are listed and a troubleshooting doc is linked for even more details on this use case.

Conclusion

With Proactive Insights, DevOpsGuru for RDS enhances its abilities to help you monitor your databases by notifying you about potential operational issues, before they become bigger problems down the road. To get started, you need to ensure that you have enabled Performance Insights on the database instance(s) you want monitored, as well as ensure and confirm that DevOps Guru is enabled to monitor those instances (for example by enabling it at account level, by monitoring specific CloudFormation stacks or by using AWS tags for specific Aurora resources). Proactive Insights is available in all regions where DevOps Guru for RDS is supported. To learn more about Proactive Insights, join us for a free hands-on Immersion Day (available in three time zones) on March 15th or April 12th.

About the authors:

Kishore Dhamodaran

Kishore Dhamodaran is a Senior Solutions Architect at AWS.

Raluca Constantin

Raluca Constantin is a Senior Database Engineer with the Relational Database Services (RDS) team at Amazon Web Services. She has 16 years of experience in the databases world. She enjoys travels, hikes, arts and is a proud mother of a 12y old daughter and a 7y old son.

Jonathan Vogel

Jonathan is a Developer Advocate at AWS. He was a DevOps Specialist Solutions Architect at AWS for two years prior to taking on the Developer Advocate role. Prior to AWS, he practiced professional software development for over a decade. Jonathan enjoys music, birding and climbing rocks.

Side-Channel Attack against CRYSTALS-Kyber

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/side-channel-attack-against-crystals-kyber.html

CRYSTALS-Kyber is one of the public-key algorithms currently recommended by NIST as part of its post-quantum cryptography standardization process.

Researchers have just published a side-channel attack—using power consumption—against an implementation of the algorithm that was supposed to be resistant against that sort of attack.

The algorithm is not “broken” or “cracked”—despite headlines to the contrary—this is just a side-channel attack. What makes this work really interesting is that the researchers used a machine-learning model to train the system to exploit the side channel.