Tag Archives: Uncategorized

More Log4j News

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/more-log4j-news.html

Log4j is being exploited by all sorts of attackers, all over the Internet:

At that point it was reported that there were over 100 attempts to exploit the vulnerability every minute. “Since we started to implement our protection we prevented over 1,272,000 attempts to allocate the vulnerability, over 46% of those attempts were made by known malicious groups,” said cybersecurity company Check Point.

And according to Check Point, attackers have now attempted to exploit the flaw on over 40% of global networks.

And a second vulnerability was found, in the patch for the first vulnerability. This is likely not to be the last.

Green information technology and classroom discussions

Post Syndicated from Gemma Coleman original https://www.raspberrypi.org/blog/green-information-technology-climate-change-data-centre-e-waste-hello-world/

The global IT industry generates as much CO2 as the aviation industry. In Hello World issue 17, we learn about the hidden impact of our IT use and the changes we can make from Beverly Clarke, national community manager for Computing at School and author of Computer Science Teacher: Insight Into the Computing Classroom.

With the onset of the pandemic, the world seemed to shut down. Flights were grounded, fewer people were commuting, and companies and individuals increased their use of technology for work and communication. On the surface, this seemed like a positive time for the environment. However, I soon found myself wondering about the impact that this increased use of technology would have on our planet, in particular the increases in energy consumption and e-waste. This is a major social, moral, and ethical issue that is hiding in plain sight — green IT is big news.

This is a major social, moral, and ethical issue that is hiding in plain sight — green IT is big news.

Energy and data centres

Thinking that online is always better for the planet is not always as straightforward as it seems. If we choose to meet via conference call rather than travelling to a meeting, there are hidden environmental impacts to consider. If there are 50 people on a call from across the globe, all of the data generated is being routed around the world through data centres, and a lot of energy is being used. If all of those people are also using video, that is even more energy than audio only.

Stacks of server hardware behind metal fencing in a data centre.
Data centres consume a lot of energy — and how is that energy generated?

Not only is the amount of energy being used a concern, but we must also ask ourselves how these data centres are being powered. Is the energy they are using coming from a renewable source? If not, we may be replacing one environmental problem with another.

What about other areas of our lives, such as taking photos or filming videos? These two activities have probably increased as we have been separated from family and friends. They use energy, especially when the image or video is then shared with others around the world and consequently routed through data centres. A large amount of energy is being used, and more is used the further the image travels.

Not only is the amount of energy being used a concern, but we must also ask ourselves how these data centres are being powered.

Similarly, consider social media and the number of posts individuals and companies make on a daily basis. All of these are travelling through data centres and using energy, yet for the most part this is not visible to the user.

E-waste

E-waste is another green IT issue, and one that will only get worse as we rely on electronic devices more. As well as the potential eyesore of mountains of e-waste, there is also the impact upon the planet of mining the precious metals used in these electronics, such as gold, copper, aluminium, and steel.

A hand holding two smartphones.
In their marketing, device manufacturers and mobile network carriers make us see the phones we currently own in a negative light so that we feel the need to upgrade to the newest model.

The processes used to mine these metals lead to pollution, and we should also consider that some of the precious metals used in our devices could run out, as there is not an endless supply in the Earth’s surface.

It is also problematic that a lot of e-waste is sent to developing countries with limited recycling plants […].

It is also problematic that a lot of e-waste is sent to developing countries with limited recycling plants, and so much of the e-waste ends up in landfill. This can lead to toxic substances being leaked into the Earth’s surface.

First steps towards action

With my reflective hat on, I started to think about discussions we as teachers could have with pupils around this topic, and came up with the following:

  • Help learners to talk about the cloud and where it is located. We can remind them that the cloud is a physical entity. Show them images of data centres to help make this real, and allow them to appreciate where the data we generate every day goes.
  • Ask learners how many photos and videos they have on their devices, and where they think those items are stored. This can be extended to a year group or whole-school exercise so they can really appreciate the sheer amount of data being used and sent across the cloud, and how data centres fit with that energy consumption. I did this activity and found that I had 7163 photos and 304 videos on my phone — that’s using a lot of energy!
A classroom of students in North America.
Helping young people gain an understanding of the impact of our use of electronic devices is an important action you can take.
  • Ask learners to research any local data centres and find out how many data centres there are in the world. You could then develop this into a discussion, including language related to data centres such as sensors, storage devices, cabling, and infrastructure. This helps learners to connect the theory to real-world examples.
  • Ask learners to reflect upon how many devices they use that are connected to the Internet of Things.
  • Consider for ourselves and ask parents, family, and friends how our online usage has changed since before the pandemic.
  • Consider what happens to electronic devices when they are thrown away and become e-waste. Where does it all go? What is the effect of e-waste on communities and countries?

Tips for greener IT

UK-based educators can watch a recent episode of TV programme Dispatches that investigates the carbon footprint of the IT industry. You can add the following tips from the programme to your discussions:

  • Turn off electronic devices when not in use
  • Use audio only when on online calls
  • Dispose of your old devices responsibly
  • Look at company websites and see what their commitment is to green IT, and consider whether we should support companies whose commitment to the planet is poor
  • Use WiFi instead of 3G/4G/5G, as it uses less energy

These lists are not exhaustive, but provide a good starting point for discussions with learners. We should all play our small part in ensuring that we #RestoreOurEarth — this year’s Earth Day theme — and having an awareness and understanding of the impact of our use of electronic devices is part of the way forward.

Some resources on green IT — do you have others?

What about you? In the comments below, share your thoughts, tips, and resources on green IT and how we can bring awareness of it to our learners and young people at home.

The post Green information technology and classroom discussions appeared first on Raspberry Pi.

Unify log aggregation and analytics across compute platforms

Post Syndicated from Hari Ohm Prasath original https://aws.amazon.com/blogs/big-data/unify-log-aggregation-and-analytics-across-compute-platforms/

Our customers want to make sure their users have the best experience running their application on AWS. To make this happen, you need to monitor and fix software problems as quickly as possible. Doing this gets challenging with the growing volume of data needing to be quickly detected, analyzed, and stored. In this post, we walk you through an automated process to aggregate and monitor logging-application data in near-real time, so you can remediate application issues faster.

This post shows how to unify and centralize logs across different computing platforms. With this solution, you can unify logs from Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Kinesis Data Firehose, and AWS Lambda using agents, log routers, and extensions. We use Amazon OpenSearch Service (successor to Amazon Elasticsearch Service) with OpenSearch Dashboards to visualize and analyze the logs, collected across different computing platforms to get application insights. You can deploy the solution using the AWS Cloud Development Kit (AWS CDK) scripts provided as part of the solution.

Customer benefits

A unified aggregated log system provides the following benefits:

  • A single point of access to all the logs across different computing platforms
  • Help defining and standardizing the transformations of logs before they get delivered to downstream systems like Amazon Simple Storage Service (Amazon S3), Amazon OpenSearch Service, Amazon Redshift, and other services
  • The ability to use Amazon OpenSearch Service to quickly index, and OpenSearch Dashboards to search and visualize logs from its routers, applications, and other devices

Solution overview

In this post, we use the following services to demonstrate log aggregation across different compute platforms:

  • Amazon EC2 – A web service that provides secure, resizable compute capacity in the cloud. It’s designed to make web-scale cloud computing easier for developers.
  • Amazon ECS – A web service that makes it easy to run, scale, and manage Docker containers on AWS, designed to make the Docker experience easier for developers.
  • Amazon EKS – A web service that makes it easy to run, scale, and manage Docker containers on AWS.
  • Kinesis Data Firehose – A fully managed service that makes it easy to stream data to Amazon S3, Amazon Redshift, or Amazon OpenSearch Service.
  • Lambda – A compute service that lets you run code without provisioning or managing servers. It’s designed to make web-scale cloud computing easier for developers.
  • Amazon OpenSearch Service – A fully managed service that makes it easy for you to perform interactive log analytics, real-time application monitoring, website search, and more.

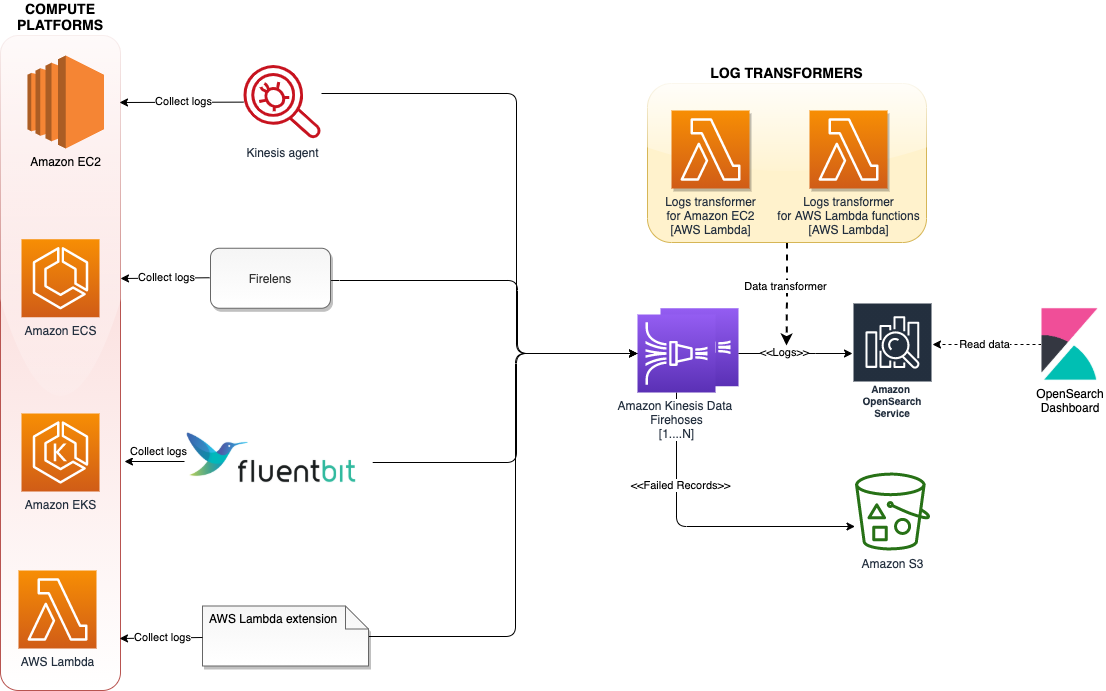
The following diagram shows the architecture of our solution.

The architecture uses various log aggregation tools such as log agents, log routers, and Lambda extensions to collect logs from multiple compute platforms and deliver them to Kinesis Data Firehose. Kinesis Data Firehose streams the logs to Amazon OpenSearch Service. Log records that fail to get persisted in Amazon OpenSearch service will get written to AWS S3. To scale this architecture, each of these compute platforms streams the logs to a different Firehose delivery stream, added as a separate index, and rotated every 24 hours.

The following sections demonstrate how the solution is implemented on each of these computing platforms.

Amazon EC2

The Kinesis agent collects and streams logs from the applications running on EC2 instances to Kinesis Data Firehose. The agent is a standalone Java software application that offers an easy way to collect and send data to Kinesis Data Firehose. The agent continuously monitors files and sends logs to the Firehose delivery stream.

BDB-1742-Ec2

The AWS CDK script provided as part of this solution deploys a simple PHP application that generates logs under the /etc/httpd/logs directory on the EC2 instance. The Kinesis agent is configured via /etc/aws-kinesis/agent.json to collect data from access_logs and error_logs, and stream them periodically to Kinesis Data Firehose (ec2-logs-delivery-stream).

Because Amazon OpenSearch Service expects data in JSON format, you can add a call to a Lambda function to transform the log data to JSON format within Kinesis Data Firehose before streaming to Amazon OpenSearch Service. The following is a sample input for the data transformer:

46.99.153.40 - - [29/Jul/2021:15:32:33 +0000] "GET / HTTP/1.1" 200 173 "-" "Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.103 Safari/537.36"

The following is our output:

{
    "logs" : "46.99.153.40 - - [29/Jul/2021:15:32:33 +0000] \"GET / HTTP/1.1\" 200 173 \"-\" \"Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.103 Safari/537.36\"",
}

We can enhance the Lambda function to extract the timestamp, HTTP, and browser information from the log data, and store them as separate attributes in the JSON document.

Amazon ECS

In the case of Amazon ECS, we use FireLens to send logs directly to Kinesis Data Firehose. FireLens is a container log router for Amazon ECS and AWS Fargate that gives you the extensibility to use the breadth of services at AWS or partner solutions for log analytics and storage.

BDB-1742-ECS

The architecture hosts FireLens as a sidecar, which collects logs from the main container running an httpd application and sends them to Kinesis Data Firehose and streams to Amazon OpenSearch Service. The AWS CDK script provided as part of this solution deploys a httpd container hosted behind an Application Load Balancer. The httpd logs are pushed to Kinesis Data Firehose (ecs-logs-delivery-stream) through the FireLens log router.

Amazon EKS

With the recent announcement of Fluent Bit support for Amazon EKS, you no longer need to run a sidecar to route container logs from Amazon EKS pods running on Fargate. With the new built-in logging support, you can select a destination of your choice to send the records to. Amazon EKS on Fargate uses a version of Fluent Bit for AWS, an upstream conformant distribution of Fluent Bit managed by AWS.

BDB-1742-EKS

The AWS CDK script provided as part of this solution deploys an NGINX container hosted behind an internal Application Load Balancer. The NGINX container logs are pushed to Kinesis Data Firehose (eks-logs-delivery-stream) through the Fluent Bit plugin.

Lambda

For Lambda functions, you can send logs directly to Kinesis Data Firehose using the Lambda extension. You can deny the records being written to Amazon CloudWatch.

BDB-1742-Lambda

After deployment, the workflow is as follows:

  1. On startup, the extension subscribes to receive logs for the platform and function events. A local HTTP server is started inside the external extension, which receives the logs.
  2. The extension buffers the log events in a synchronized queue and writes them to Kinesis Data Firehose via PUT records.
  3. The logs are sent to downstream systems.
  4. The logs are sent to Amazon OpenSearch Service.

The Firehose delivery stream name gets specified as an environment variable (AWS_KINESIS_STREAM_NAME).

For this solution, because we’re only focusing on collecting the run logs of the Lambda function, the data transformer of the Kinesis Data Firehose delivery stream filters out the records of type function ("type":"function") before sending it to Amazon OpenSearch Service.

The following is a sample input for the data transformer:

[
   {
      "time":"2021-07-29T19:54:08.949Z",
      "type":"platform.start",
      "record":{
         "requestId":"024ae572-72c7-44e0-90f5-3f002a1df3f2",
         "version":"$LATEST"
      }
   },
   {
      "time":"2021-07-29T19:54:09.094Z",
      "type":"platform.logsSubscription",
      "record":{
         "name":"kinesisfirehose-logs-extension-demo",
         "state":"Subscribed",
         "types":[
            "platform",
            "function"
         ]
      }
   },
   {
      "time":"2021-07-29T19:54:09.096Z",
      "type":"function",
      "record":"2021-07-29T19:54:09.094Z\tundefined\tINFO\tLoading function\n"
   },
   {
      "time":"2021-07-29T19:54:09.096Z",
      "type":"platform.extension",
      "record":{
         "name":"kinesisfirehose-logs-extension-demo",
         "state":"Ready",
         "events":[
            "INVOKE",
            "SHUTDOWN"
         ]
      }
   },
   {
      "time":"2021-07-29T19:54:09.097Z",
      "type":"function",
      "record":"2021-07-29T19:54:09.097Z\t024ae572-72c7-44e0-90f5-3f002a1df3f2\tINFO\tvalue1 = value1\n"
   },   
   {
      "time":"2021-07-29T19:54:09.098Z",
      "type":"platform.runtimeDone",
      "record":{
         "requestId":"024ae572-72c7-44e0-90f5-3f002a1df3f2",
         "status":"success"
      }
   }
]

Prerequisites

To implement this solution, you need the following prerequisites:

Build the code

Check out the AWS CDK code by running the following command:

mkdir unified-logs && cd unified-logs
git clone https://github.com/aws-samples/unified-log-aggregation-and-analytics .

Build the lambda extension by running the following command:

cd lib/computes/lambda/extensions
chmod +x extension.sh
./extension.sh
cd ../../../../

Make sure to replace default AWS region specified under the value of firehose.endpoint attribute inside lib/computes/ec2/ec2-startup.sh.

Build the code by running the following command:

yarn install && npm run build

Deploy the code

If you’re running AWS CDK for the first time, run the following command to bootstrap the AWS CDK environment (provide your AWS account ID and AWS Region):

cdk bootstrap \
    --cloudformation-execution-policies arn:aws:iam::aws:policy/AdministratorAccess \
    aws://<AWS Account Id>/<AWS_REGION>

You only need to bootstrap the AWS CDK one time (skip this step if you have already done this).

Run the following command to deploy the code:

cdk deploy --requires-approval

You get the following output:

 ✅  CdkUnifiedLogStack

Outputs:
CdkUnifiedLogStack.ec2ipaddress = xx.xx.xx.xx
CdkUnifiedLogStack.ecsloadbalancerurl = CdkUn-ecsse-PY4D8DVQLK5H-xxxxx.us-east-1.elb.amazonaws.com
CdkUnifiedLogStack.ecsserviceLoadBalancerDNS570CB744 = CdkUn-ecsse-PY4D8DVQLK5H-xxxx.us-east-1.elb.amazonaws.com
CdkUnifiedLogStack.ecsserviceServiceURL88A7B1EE = http://CdkUn-ecsse-PY4D8DVQLK5H-xxxx.us-east-1.elb.amazonaws.com
CdkUnifiedLogStack.eksclusterClusterNameCE21A0DB = ekscluster92983EFB-d29892f99efc4419bc08534a3d253160
CdkUnifiedLogStack.eksclusterConfigCommand515C0544 = aws eks update-kubeconfig --name ekscluster92983EFB-d29892f99efc4419bc08534a3d253160 --region us-east-1 --role-arn arn:aws:iam::xxx:role/CdkUnifiedLogStack-clustermasterroleCD184EDB-12U2TZHS28DW4
CdkUnifiedLogStack.eksclusterGetTokenCommand3C33A2A5 = aws eks get-token --cluster-name ekscluster92983EFB-d29892f99efc4419bc08534a3d253160 --region us-east-1 --role-arn arn:aws:iam::xxx:role/CdkUnifiedLogStack-clustermasterroleCD184EDB-12U2TZHS28DW4
CdkUnifiedLogStack.elasticdomainarn = arn:aws:es:us-east-1:xxx:domain/cdkunif-elasti-rkiuv6bc52rp
CdkUnifiedLogStack.s3bucketname = cdkunifiedlogstack-logsfailederrcapturebucket0bcc-xxxxx
CdkUnifiedLogStack.samplelambdafunction = CdkUnifiedLogStack-LambdatransformerfunctionFA3659-c8u392491FrW

Stack ARN:
arn:aws:cloudformation:us-east-1:xxxx:stack/CdkUnifiedLogStack/6d53ef40-efd2-11eb-9a9d-1230a5204572

AWS CDK takes care of building the required infrastructure, deploying the sample application, and collecting logs from different sources to Amazon OpenSearch Service.

The following is some of the key information about the stack:

  • ec2ipaddress – The public IP address of the EC2 instance, deployed with the sample PHP application
  • ecsloadbalancerurl – The URL of the Amazon ECS Load Balancer, deployed with the httpd application
  • eksclusterClusterNameCE21A0DB – The Amazon EKS cluster name, deployed with the NGINX application
  • samplelambdafunction – The sample Lambda function using the Lambda extension to send logs to Kinesis Data Firehose
  • opensearch-domain-arn – The ARN of the Amazon OpenSearch Service domain

Generate logs

To visualize the logs, you first need to generate some sample logs.

  1. To generate Lambda logs, invoke the function using the following AWS CLI command (run it a few times):
aws lambda invoke \
--function-name "<<samplelambdafunction>>" \
--payload '{"payload": "hello"}' /tmp/invoke-result \
--cli-binary-format raw-in-base64-out \
--log-type Tail

Make sure to replace samplelambdafunction with the actual Lambda function name. The file path needs to be updated based on the underlying operating system.

The function should return "StatusCode": 200, with the following output:

{
    "StatusCode": 200,
    "LogResult": "<<Encoded>>",
    "ExecutedVersion": "$LATEST"
}
  1. Run the following command a couple of times to generate Amazon EC2 logs:
curl http://ec2ipaddress:80

Make sure to replace ec2ipaddress with the public IP address of the EC2 instance.

  1. Run the following command a couple of times to generate Amazon ECS logs:
curl http://ecsloadbalancerurl:80

Make sure to replace ecsloadbalancerurl with the public ARN of the AWS Application Load Balancer.

We deployed the NGINX application with an internal load balancer, so the load balancer hits the health checkpoint of the application, which is sufficient to generate the Amazon EKS access logs.

Visualize the logs

To visualize the logs, complete the following steps:

  1. On the Amazon OpenSearch Service console, choose the hyperlink provided for the OpenSearch Dashboard 7URL.
  2. Configure access to the OpenSearch Dashboard.
  3. Under OpenSearch Dashboard, on the Discover menu, start creating a new index pattern for each compute log.

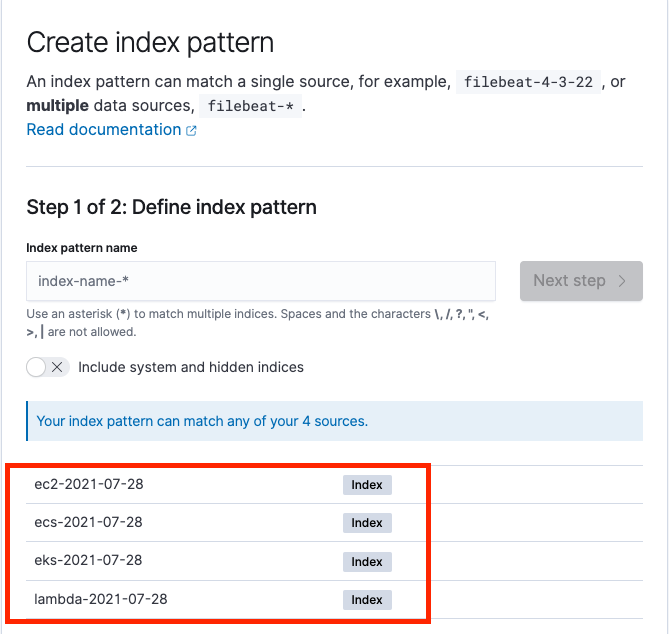
We can see separate indexes for each compute log partitioned by date, as in the following screenshot.

BDB-1742-create-index

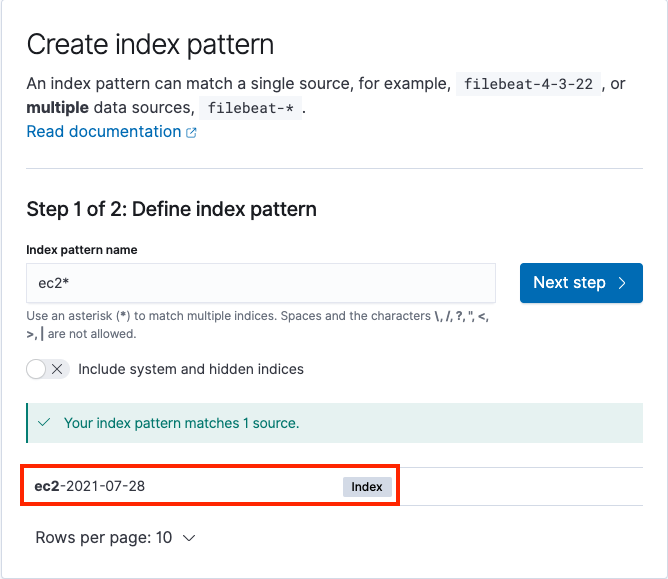
The following screenshot shows the process to create index patterns for Amazon EC2 logs.

BDB-1742-ec2

After you create the index pattern, we can start analyzing the logs using the Discover menu under OpenSearch Dashboard in the navigation pane. This tool provides a single searchable and unified interface for all the records with various compute platforms. We can switch between different logs using the Change index pattern submenu.

BDB-1742-unified

Clean up

Run the following command from the root directory to delete the stack:

cdk destroy

Conclusion

In this post, we showed how to unify and centralize logs across different compute platforms using Kinesis Data Firehose and Amazon OpenSearch Service. This approach allows you to analyze logs quickly and the root cause of failures, using a single platform rather than different platforms for different services.

If you have feedback about this post, submit your comments in the comments section.

Resources

For more information, see the following resources:


About the author

HariHari Ohm Prasath is a Senior Modernization Architect at AWS, helping customers with their modernization journey to become cloud native. Hari loves to code and actively contributes to the open source initiatives. You can find him in Medium, Github & Twitter @hariohmprasath.

balluBallu Singh is a Principal Solutions Architect at AWS. He lives in the San Francisco Bay area and helps customers architect and optimize applications on AWS. In his spare time, he enjoys reading and spending time with his family.
Upcoming Speaking Engagements

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2021/12/upcoming-speaking-engagements-15.html

This is a current list of where and when I am scheduled to speak:

  • I’m speaking at the RSA Conference 2022 in San Francisco on February 8, 2022.
  • I’m speaking at IT-S Now 2022 in Vienna on June 2, 2022.
  • I’m speaking at the 14th International Conference on Cyber Conflict, CyCon 2022, in Tallinn, Estonia on June 3, 2022.

The list is maintained on this page.

On the Log4j Vulnerability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/on-the-log4j-vulnerability.html

It’s serious:

The range of impacts is so broad because of the nature of the vulnerability itself. Developers use logging frameworks to keep track of what happens in a given application. To exploit Log4Shell, an attacker only needs to get the system to log a strategically crafted string of code. From there they can load arbitrary code on the targeted server and install malware or launch other attacks. Notably, hackers can introduce the snippet in seemingly benign ways, like by sending the string in an email or setting it as an account username.

Threat advisory from Cisco. Cloudflare found it in the wild before it was disclosed. CISA is very concerned, saying that hundreds of millions of devices are likely affected.

NSO Group’s Pegasus Spyware Used Against US State Department Officials

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/nso-groups-pegasus-spyware-used-against-us-state-department-officials.html

NSO Group’s descent into Internet pariah status continues. Its Pegasus spyware was used against nine US State Department employees. We don’t know which NSO Group customer trained the spyware on the US. But the company does:

NSO Group said in a statement on Thursday that it did not have any indication their tools were used but canceled access for the relevant customers and would investigate based on the Reuters inquiry.

“If our investigation shall show these actions indeed happened with NSO’s tools, such customer will be terminated permanently and legal actions will take place,” said an NSO spokesperson, who added that NSO will also “cooperate with any relevant government authority and present the full information we will have.”

Google Shuts Down Glupteba Botnet, Sues Operators

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/google-shuts-down-glupteba-botnet-sues-operators.html

Google took steps to shut down the Glupteba botnet, at least for now. (The botnet uses the bitcoin blockchain as a backup command-and-control mechanism, making it hard to get rid of it permanently.) So Google is also suing the botnet’s operators.

It’s an interesting strategy. Let’s see if it’s successful.

New German Government is Pro-Encryption and Anti-Backdoors

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/new-german-government-is-pro-encryption-and-anti-backdoors.html

I hope this is true:

According to Jens Zimmermann, the German coalition negotiations had made it “quite clear” that the incoming government of the Social Democrats (SPD), the Greens and the business-friendly liberal FDP would reject “the weakening of encryption, which is being attempted under the guise of the fight against child abuse” by the coalition partners.

Such regulations, which are already enshrined in the interim solution of the ePrivacy Regulation, for example, “diametrically contradict the character of the coalition agreement” because secure end-to-end encryption is guaranteed there, Zimmermann said.

Introducing backdoors would undermine this goal of the coalition agreement, he added.

I have written about this.

Someone Is Running Lots of Tor Relays

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/someone-is-running-lots-of-tor-relays.html

Since 2017, someone is running about a thousand — 10% of the total — Tor servers in an attempt to deanonymize the network:

Grouping these servers under the KAX17 umbrella, Nusenu says this threat actor has constantly added servers with no contact details to the Tor network in industrial quantities, operating servers in the realm of hundreds at any given point.

The actor’s servers are typically located in data centers spread all over the world and are typically configured as entry and middle points primarily, although KAX17 also operates a small number of exit points.

Nusenu said this is strange as most threat actors operating malicious Tor relays tend to focus on running exit points, which allows them to modify the user’s traffic. For example, a threat actor that Nusenu has been tracking as BTCMITM20 ran thousands of malicious Tor exit nodes in order to replace Bitcoin wallet addresses inside web traffic and hijack user payments.

KAX17’s focus on Tor entry and middle relays led Nusenu to believe that the group, which he described as “non-amateur level and persistent,” is trying to collect information on users connecting to the Tor network and attempting to map their routes inside it.

In research published this week and shared with The Record, Nusenu said that at one point, there was a 16% chance that a Tor user would connect to the Tor network through one of KAX17’s servers, a 35% chance they would pass through one of its middle relays, and up to 5% chance to exit through one.

Slashdot thread.

How to set up Amazon Quicksight dashboard for Amazon Pinpoint and Amazon SES engagement events

Post Syndicated from satyaso original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-set-up-amazon-quicksight-dashboard-for-amazon-pinpoint-and-amazon-ses-events/

In this post, we will walk through using Amazon Pinpoint and Amazon Quicksight to create customizable messaging campaign reports. Amazon Pinpoint is a flexible and scalable outbound and inbound marketing communications service that allows customers to connect with users over channels like email, SMS, push, or voice. Amazon QuickSight is a scalable, serverless, embeddable, machine learning-powered business intelligence (BI) service built for the cloud. This solution allows event and user data from Amazon Pinpoint to flow into Amazon Quicksight. Once in Quicksight, customers can build their own reports that shows campaign performance on a more granular level.

Engagement Event Dashboard

Customers want to view the results of their messaging campaigns in ever increasing levels of granularity and ensure their users see value from the email, SMS or push notifications they receive. Customers also want to analyze how different user segments respond to different messages, and how to optimize subsequent user communication. Previously, customers could only view this data in Amazon Pinpoint analytics, which offers robust reporting on: events, funnels, and campaigns. However, does not allow analysis across these different parameters and the building of custom reports. For example, show campaign revenue across different user segments, or show what events were generated after a user viewed a campaign in a funnel analysis. Customers would need to extract this data themselves and do the analysis in excel.

Prerequisites

  • Digital user engagement event database solution must be setup at 1st.
  • Customers should be prepared to purchase Amazon Quicksight because it has its own set of costs which is not covered within Amazon Pinpoint cost.

Solution Overview

This Solution uses the Athena tables created by Digital user engagement events database solution. The AWS CloudFormation template given in this post automatically sets up the different architecture components, to capture detailed notifications about Amazon Pinpoint engagement events and log those in Amazon Athena in the form of Athena views. You still need to manually configure Amazon Quicksight dashboards to link to these newly generated Athena views. Please follow the steps below in order for further information.

Use case(s)

Event dashboard solutions have following use cases: –

  • Deep dive into engagement insights. (eg: SMS events, Email events, Campaign events, Journey events)
  • The ability to view engagement events at the individual user level.
  • Data/process mining turn raw event data into useful marking insights.
  • User engagement benchmarking and end user event funneling.
  • Compute campaign conversions (post campaign user analysis to show campaign effectiveness)
  • Build funnels that shows user progression.

Getting started with solution deployment

Prerequisite tasks to be completed before deploying the logging solution

Step 1 – Create AWS account, Pinpoint Project, Implement Event-Database-Solution.
As part of this step customers need to implement DUE Event database solution as the current solution (DUE event dashboard) is an extension of DUE event database solution. The basic assumption here is that the customer has already configured Amazon Pinpoint project or Amazon SES within the required AWS region before implementing this step.

The steps required to implement an event dashboard solution are as follows.

a/Follow the steps mentioned in Event database solution to implement the complete stack. Prior installing the complete stack copy and save the name Athena events database name as shown in the diagram. For my case it is due_eventdb. Database name is required as an input parameter for the current Event Dashboard solution.

b/Once the solution is deployed, navigate to the output page of the cloud formation stack, and copy, and save the following information, which will be required as input parameters in step 2 of the current Event Dashboard solution.

Step 2 – Deploy Cloud formation template for Event dashboard solution
This step generates a number of new Amazon Athena views that will serve as a data source for Amazon Quicksight. Continue with the following actions.

  • Download the cloud formation template(“Event-dashboard.yaml”) from AWS samples.
  • Navigate to Cloud formation page in AWS console, click up right on “Create stack” and select the option “With new resources (standard)”
  • Leave the “Prerequisite – Prepare template” to “Template is ready” and for the “Specify template” option, select “Upload a template file”. On the same page, click on “Choose file”, browse to find the file “Event-dashboard.yaml” file and select it. Once the file is uploaded, click “Next” and deploy the stack.

  • Enter following information under the section “Specify stack details”:
    • EventAthenaDatabaseName – As mentioned in Step 1-a.
    • S3DataLogBucket- As mentioned in Step 1-b
    • This solution will create additional 5 Athena views which are
      • All_email_events
      • All_SMS_events
      • All_custom_events (Custom events can be Mobile app/WebApp/Push Events)
      • All_campaign_events
      • All_journey_events

Step 3 – Create Amazon Quicksight engagement Dashboard
This step walks you through the process of creating an Amazon Quicksight dashboard for Amazon Pinpoint engagement events using the Athena views you created in step-2

  1. To Setup Amazon Quicksight for the 1st time please follow this link (this process is not needed if you have already setup Amazon Quicksight). Please make sure you are an Amazon Quicksight Administrator.
  2. Go/search Amazon Quicksight on AWS console.
  3. Create New Analysis and then select “New dataset”
  4. Select Athena as data source
  5. As a next step, you need to select what all analysis you need for respective events. This solution provides option to create 5 different set of analysis as mentioned in Step 2. They are a/All email events, b/All SMS Events, c/All Custom Events (Mobile/Web App, web push etc), d/ All Campaign events, e/All Journey events. Dashboard can be created from Quicksight analysis and same can be shared among the organization stake holders. Following are the steps to create analysis and dashboards for different type of events.
  6. Email Events –
    • For all email events, name the analysis “All-emails-events” (this can be any kind of customer preferred nomenclature), select Athena workgroup as primary, and then create a data source.
    • Once you create the data source Quicksight lists all the views and tables available under the specified database (in our case it is:-  due_eventdb). Select the email_all_events view as data source.
    • Select the event data location for analysis. There are mainly two options available which are a/ Import to Spice quicker analysis b/ Directly query your data. Please select the preferred options and then click on “visualize the data”.
    • Import to Spice quicker analysis – SPICE is the Amazon QuickSight Super-fast, Parallel, In-memory Calculation Engine. It’s engineered to rapidly perform advanced calculations and serve data. In Enterprise edition, data stored in SPICE is encrypted at rest. (1 GB of storage is available for free for extra storage customer need to pay extra, please refer cost section in this document )
    • Directly query your data – This process enables Quicksight to query directly to the Athena or source database (In the current case it is Athena) and Quicksight will not store any data.
    • Now that you have selected a data source, you will be taken to a blank quick sight canvas (Blank analysis page) as shown in the following Image, please drag and drop what visualization type you need to visualize onto the auto-graph pane. Please note that Amazon QuickSight is a Busines intelligence platform, so customers are free to choose the desired visualization types to observe the individual engagement events.
    • As part of this blog, we have displayed how to create some simple analysis graphs to visualize the engagement events.
    • As an initial step please Select tabular Visualization as shown in the Image.
    • Select all the event dimensions that you want to put it as part of the Table in X axis. Amazon Quicksight table can be extended to show as many as tables columns, this completely depends upon the business requirement how much data marketers want to visualize.
    • Further filtering on the table can be done using Quicksight filters, you can apply the filter on specific granular values to enable further filtering. For Eg – If you want to apply filtering on the destination email Id then 1/Select the filter from left hand menu 2/Add destination field as the filtering criterion 3/ Tick on the destination field you are trying to filter or search for the Destination email ID that 4/ All the result in the table gets further filtered as per the filter criterion
    • As a next step please add another visual from top left corner “Add -> Add Visual”, then select the Donut Chart from Visual types pane. Donut charts are always used for displaying aggregation.
    • Then select the “event_type” as the Group to visualize the aggregated events, this helps marketers/business users to figure out how many email events occurred and what are the aggregated success ratio, click ratio, complain ratio or bounce ratio etc for the emails/Campaign that’s sent to end users.
    • To create a Quicksight dashboards from the Quicksight analysis click Share menu option at the top right corner then select publish dashboard”. Provide required dashboard name while publishing the dashboard”. Same dashboard can be shared with multiple audiences in the Organization.
    • Following is the final version of the dashboard. As mentioned above Quicksight dashboards can be shared with other stakeholders and also complete dashboard can be exported as excel sheet.
  7. SMS Events-
    • As shown above SMS events can be analyzed using Quicksight and dash boards can be created out of the analysis. Please repeat all of the sub-steps listed in step 6. Following is a sample SMS dashboard.
  8. Custom Events-
    • After you integrate your application (app) with Amazon Pinpoint, Amazon Pinpoint can stream event data about user activity, different type custom events, and message deliveries for the app. Eg :- Session.start, Product_page_view, _session.stop etc. Do repeat all of the sub-steps listed in step 6 create a custom event dashboards.
  9. Campaign events
    • As shown before campaign also can be included in the same dashboard or you can create new dashboard only for campaign events.

Cost for Event dashboard solution
You are responsible for the cost of the AWS services used while running this solution. As of the date of publication, the cost for running this solution with default settings in the US West (Oregon) Region is approximately $65 a month. The cost estimate includes the cost of AWS Lambda, Amazon Athena, Amazon Quicksight. The estimate assumes querying 1TB of data in a month, and two authors managing Amazon Quicksight every month, four Amazon Quicksight readers witnessing the events dashboard unlimited times in a month, and a Quicksight spice capacity is 50 GB per month. Prices are subject to change. For full details, see the pricing webpage for each AWS service you will be using in this solution.

Clean up

When you’re done with this exercise, complete the following steps to delete your resources and stop incurring costs:

  1. On the CloudFormation console, select your stack and choose Delete. This cleans up all the resources created by the stack,
  2. Delete the Amazon Quicksight Dashboards and data sets that you have created.

Conclusion

In this blog post, I have demonstrated how marketers, business users, and business analysts can utilize Amazon Quicksight dashboards to evaluate and exploit user engagement data from Amazon SES and Pinpoint event streams. Customers can also utilize this solution to understand how Amazon Pinpoint campaigns lead to business conversions, in addition to analyzing multi-channel communication metrics at the individual user level.

Next steps

The personas for this blog are both the tech team and the marketing analyst team, as it involves a code deployment to create very simple Athena views, as well as the steps to create an Amazon Quicksight dashboard to analyse Amazon SES and Amazon Pinpoint engagement events at the individual user level. Customers may then create their own Amazon Quicksight dashboards to illustrate the conversion ratio and propensity trends in real time by integrating campaign events with app-level events such as purchase conversions, order placement, and so on.

Extending the solution

You can download the AWS Cloudformation templates, code for this solution from our public GitHub repository and modify it to fit your needs.


About the Author


Satyasovan Tripathy works at Amazon Web Services as a Senior Specialist Solution Architect. He is based in Bengaluru, India, and specialises on the AWS Digital User Engagement product portfolio. He likes reading and travelling outside of work.

Thieves Using AirTags to “Follow” Cars

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/thieves-using-airtags-to-follow-cars.html

From Ontario and not surprising:

Since September 2021, officers have investigated five incidents where suspects have placed small tracking devices on high-end vehicles so they can later locate and steal them. Brand name “air tags” are placed in out-of-sight areas of the target vehicles when they are parked in public places like malls or parking lots. Thieves then track the targeted vehicles to the victim’s residence, where they are stolen from the driveway.

Thieves typically use tools like screwdrivers to enter the vehicles through the driver or passenger door, while ensuring not to set off alarms. Once inside, an electronic device, typically used by mechanics to reprogram the factory setting, is connected to the onboard diagnostics port below the dashboard and programs the vehicle to accept a key the thieves have brought with them. Once the new key is programmed, the vehicle will start and the thieves drive it away.

I’m not sure if there’s anything that can be done:

When Apple first released AirTags earlier this year, concerns immediately sprung up about nefarious use cases for the covert trackers. Apple responded with a slew of anti-stalking measures, but those are more intended for keeping people safe than cars. An AirTag away from its owner will sound an alarm, letting anyone nearby know that it’s been left behind, but it can take up to 24 hours for that alarm to go off — more than enough time to nab a car in the dead of night.

За маските и хората

Post Syndicated from Grigor Gatchev – A Weblog original http://www.gatchev.info/blog/?p=2403

– Ей, момиче! Не е редно маската ти да е под носа!

Дрезгавият глас на стареца на опашката пред мен ме изтръгна от мислите ми. Бяхме стигнали до касата, и маската на касиерката наистина покриваше само устата ѝ.

– Няма ли да си я оправиш?

– Не съм ви никаква, че да ми говорите на ти! – отвърна момичето и гордо вирна глава.

Огледах се. Маските и на тримата на опашката зад мен също бяха под носовете им. Очевидно беше нещо като традиция в магазинчето, в което бях влязъл случайно.

Да направя нещо, за да не започне скандал? Като минимум бързам и ще ме забави…

– Не се безпокойте, господине. При такива инфекции, ако човек не киха, носът е на практика само входна врата. Покрива ли маската устата, няма да ви зарази. – Не беше абсолютно точно вярно, но все пак може би щеше да успокои дядото.

Той се обърна, изгледа ме, кимна ми, хвърли на тезгяха няколко монети и излезе с покупката си. Аз също платих набързо, изскочих от магазина… и насмалко да си скъсам якето – успях неясно как да закача вътрешния му джоб на дръжката на вратата.

Докато го откачах, погледът ми падна върху останалите вътре. Касиерката тъкмо дръпваше маската върху носа си. Точно същото правеха и хората от опашката.

Защо?! Вече при тях нямаше никой, който да им създаде проблем!… ?!

Чак тогава ми просветна какво всъщност съм им казал. „Като си държите маските под носа, създавате проблем само на себе си. Така че вие се минавате, не околните.“

За да носят маските под носа си, значи не са вярвали, че са особено нужни. Може би дори не са вярвали, че има вируси и епидемия. Но в момента, в който им беше „намекнато“, че те се минават, моментално си ги оправиха. Страхът да не се минат се оказа по-силен от логиката, каквато можеха да я проумеят…

Просто случка, каквато се случи. И изводите ми от нея – каквито си ги направих.

Testing Faraday Cages

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/testing-faraday-cages.html

Matt Blaze tested a variety of Faraday cages for phones, both commercial and homemade.

The bottom line:

A quick and likely reliable “go/no go test” can be done with an Apple AirTag and an iPhone: drop the AirTag in the bag under test, and see if the phone can locate it and activate its alarm (beware of caching in the FindMy app when doing this).

This test won’t tell you the exact attenuation level, of course, but it will tell you if the attenuation is sufficient for most practical purposes. It can also detect whether an otherwise good bag has been damaged and compromised.

At least in the frequency ranges I tested, two commercial Faraday pouches (the EDEC OffGrid and Mission Darkness Window pouches) yielded excellent performance sufficient to provide assurance of signal isolation under most real-world circumstances. None of the makeshift solutions consistently did nearly as well, although aluminum foil can, under ideal circumstances (that are difficult to replicate) sometimes provide comparable levels of attenuation.

Smart Contract Bug Results in $31 Million Loss

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/12/smart-contract-bug-results-in-31-million-loss.html

A hacker stole $31 million from the blockchain company MonoX Finance , by exploiting a bug in software the service uses to draft smart contracts.

Specifically, the hack used the same token as both the tokenIn and tokenOut, which are methods for exchanging the value of one token for another. MonoX updates prices after each swap by calculating new prices for both tokens. When the swap is completed, the price of tokenIn­that is, the token sent by the user­decreases and the price of tokenOut­or the token received by the user­increases.

By using the same token for both tokenIn and tokenOut, the hacker greatly inflated the price of the MONO token because the updating of the tokenOut overwrote the price update of the tokenIn. The hacker then exchanged the token for $31 million worth of tokens on the Ethereum and Polygon blockchains.

The article goes on to talk about how common these sorts of attacks are. The basic problem is that the code is the ultimate authority — there is no adjudication protocol — so if there’s a vulnerability in the code, there is no recourse. And, of course, there are lots of vulnerabilities in code.

To me, this is reason enough never to use smart contracts for anything important. Human-based adjudication systems are not useless pre-Internet human baggage, they’re vital.

Announcing winners of the AWS Graviton Challenge Contest and Hackathon

Post Syndicated from Neelay Thaker original https://aws.amazon.com/blogs/compute/announcing-winners-of-the-aws-graviton-challenge-contest-and-hackathon/

At AWS, we are constantly innovating on behalf of our customers so they can run virtually any workload, with optimal price and performance. Amazon EC2 now includes more than 475 instance types that offer a choice of compute, memory, networking, and storage to suit your workload needs. While we work closely with our silicon partners to offer instances based on their latest processors and accelerators, we also drive more choice for our customers by building our own silicon.

The AWS Graviton family of processors were built as part of that silicon innovation initiative with the goal of pushing the price performance envelope for a wide variety of customer workloads in EC2. We now have 12 EC2 instance families powered by AWS Graviton2 processors – general purpose (M6g, M6gd), burstable (T4g), compute optimized (C6g, C6gd, C6gn), memory optimized (R6g, R6gd, X2gd), storage optimized (Im4gn, Is4gen), and accelerated computing (G5g) available globally across 23 AWS Regions. We also announced the preview of Amazon EC2 C7g instances powered by the latest generation AWS Graviton3 processors that will provide the best price performance for compute-intensive workloads in EC2. Thousands of customers, including Discovery, DIRECTV, Epic Games, and Formula 1, have realized significant price performance benefits with AWS Graviton-based instances for a broad range of workloads. This year, AWS Graviton-based instances also powered much of Amazon Prime Day 2021 and supported 12 core retail services during the massive 2-day online shopping event.

To make it easy for customers to adopt Graviton-based instances, we launched a program called the Graviton Challenge. Working with customers, we saw that many successful adoptions of Graviton-based instances were the result of one or two developers taking a single workload and spending a few days to benchmark the price performance gains with Graviton2-based instances, before scaling it to more workloads. The Graviton Challenge provides a step-by-step plan that developers can follow to move their first workload to Graviton-based instances. With the Graviton Challenge, we also launched a Contest (US-only), and then a Hackathon (global), where developers could compete for prizes by building new applications or moving existing applications to run on Graviton2-based instances. More than a thousand participants, including enterprises, startups, individual developers, open-source developers, and Arm developers, registered and ran a variety of applications on Graviton-based instances with significant price performance benefits. We saw some fantastic entries and usage of Graviton2-based instances across a variety of use cases and want to highlight a few.

The Graviton Challenge Contest winners:

  • Best Adoption – Enterprise and Most Impactful Adoption: VMware vRealize SRE team, who migrated 60 micro-services written in Java, Rust, and Golang to Graviton2-based general purpose and compute optimized instances and realized up to 48% latency reduction and 22% cost savings.
  • Best Adoption – Startup: Kasm Technologies, who realized up to 48% better performance and 25% potential cost savings for its container streaming platform built on C/C++ and Python.
  • Best New Workload adoption: Dustin Wilson, who built a dynamic tile server based on Golang and running on Graviton2-based memory-optimized instances that helps analysts query large geospatial datasets and benchmarked up to 1.8x performance gains over comparable x86-based instances.
  • Most Innovative Adoption: Loroa, an application that translates any given text into spoken words from one language into multiple other languages using Graviton2-based instances, Amazon Polly, and Amazon Translate.

If you are attending AWS re:Invent 2021 in person, you can hear more details on their Graviton adoption experience by attending the CMP213: Lessons learned from customers who have adopted AWS Graviton chalk talk.

Winners for the Graviton Challenge Hackathon:

  • Best New App: PickYourPlace, an open-source based data analytics platform to help users select a place to live based on property value, safety, and accessibility.
  • Best Migrated App: Genie, an image credibility checker based on deep learning that makes predictions on photographic and tampered confidence of an image.
  • Highest Potential Impact: Welly Tambunan, who’s also an AWS Community Builder, for porting big data platforms Spark, Dremio, and AirByte to Graviton2 instances so developers can leverage it to build big data capabilities into their applications.
  • Most Creative Use Case: OXY, a low-cost custom Oximeter with mobile and web apps that enables continuous and remote monitoring to prevent deaths due to Silent Hypoxia.
  • Best Technical Implementation: Apollonia Bot that plays songs, playlists, or podcasts on a Discord voice channel, so users can listen to it together.

It’s been incredibly exciting to see the enthusiasm and benefits realized by our customers. We are also thankful to our judges – Patrick Moorhead from Moor Insights, James Governor from RedMonk, and Jason Andrews from Arm, for their time and effort.

In addition to EC2, several AWS services for databases, analytics, and even serverless support options to run on Graviton-based instances. These include Amazon Aurora, Amazon RDS, Amazon MemoryDB, Amazon DocumentDB, Amazon Neptune, Amazon ElastiCache, Amazon OpenSearch, Amazon EMR, AWS Lambda, and most recently, AWS Fargate. By using these managed services on Graviton2-based instances, customers can get significant price performance gains with minimal or no code changes. We also added support for Graviton to key AWS infrastructure services such as Elastic Beanstalk, Amazon EKS, Amazon ECS, and Amazon CloudWatch to help customers build, run, and scale their applications on Graviton-based instances. Additionally, a large number of Linux and BSD-based operating systems, and partner software for security, monitoring, containers, CI/CD, and other use cases now support Graviton-based instances and we recently launched the AWS Graviton Ready program as part of the AWS Service Ready program to offer Graviton-certified and validated solutions to customers.

Congrats to all of our Contest and Hackathon winners! Full list of the Contest and Hackathon winners is available on the Graviton Challenge page.

P.S.: Even though the Contest and Hackathon have ended, developers can still access the step-by-step plan on the Graviton Challenge page to move their first workload to Graviton-based instances.

Intel Is Maintaining Legacy Technology for Security Research

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/11/intel-is-maintaining-legacy-technology-for-security-research.html

Interesting:

Intel’s issue reflects a wider concern: Legacy technology can introduce cybersecurity weaknesses. Tech makers constantly improve their products to take advantage of speed and power increases, but customers don’t always upgrade at the same pace. This creates a long tail of old products that remain in widespread use, vulnerable to attacks.

Intel’s answer to this conundrum was to create a warehouse and laboratory in Costa Rica, where the company already had a research-and-development lab, to store the breadth of its technology and make the devices available for remote testing. After planning began in mid-2018, the Long-Term Retention Lab was up and running in the second half of 2019.

The warehouse stores around 3,000 pieces of hardware and software, going back about a decade. Intel plans to expand next year, nearly doubling the space to 27,000 square feet from 14,000, allowing the facility to house 6,000 pieces of computer equipment.

Intel engineers can request a specific machine in a configuration of their choice. It is then assembled by a technician and accessible through cloud services. The lab runs 24 hours a day, seven days a week, typically with about 25 engineers working any given shift.

Slashdot thread.