Tag Archives: Elastic Load Balancing

Automating post-quantum cryptography readiness using AWS Config

Post Syndicated from Pravin Nair original https://aws.amazon.com/blogs/security/automating-post-quantum-cryptography-readiness-using-aws-config/

Migrating your TLS endpoints to Post-quantum cryptography (PQC) starts with understanding your current TLS endpoint inventory and posture. This post introduces the PQC Readiness Scanner — an automated tool that inventories your Application Load Balancer (ALB), Network Load Balancer (NLB), and Amazon API Gateway endpoints and continuously monitors their TLS configurations for PQC readiness. The scanner classifies each endpoint into a three-tier framework that helps prioritize and plan PQC migration.

As quantum computing advances, you need to migrate to quantum-resistant cryptography to protect your data long-term. The PQC Readiness Scanner helps you identify which endpoints to migrate first and tracks your progress across accounts. For web traffic, PQC key exchange algorithms are negotiated only within TLS 1.3. This means quantum-resistant connections require endpoints that support TLS 1.3 and PQC key exchange.

Under the AWS Shared Responsibility Model, AWS secures the infrastructure and enables PQC support across its services. Customers are responsible for configuring their resources to use PQC-capable TLS policies. For AWS-terminated TLS connections—such as those on Application Load Balancer (ALB), Network Load Balancer (NLB), Amazon API Gateway, and Amazon CloudFront—customers choose the security policy (an AWS-managed configuration defining supported TLS protocol versions and cipher suites for a listener) that determines TLS version and cipher suite, key exchange, and authentication algorithm support.

The automated PQC Readiness Scanner for AWS-terminated TLS endpoints is built using AWS Config conformance packs. A conformance pack is a collection of AWS Config rules and remediation actions that can be deployed as a single entity in an account and a Region or across an organization in AWS Organizations.

Solution overview

The PQC Readiness Scanner deploys AWS Config rules using a conformance pack to evaluate the security policy on each endpoint. Based on the evaluation, each resource is classified into a three-tier readiness framework that prioritizes migration actions needed to achieve PQ-ready TLS.

The PQC Readiness Scanner performs two checks per resource:

  1. Does the endpoint use a PQ-ready security policy?
  2. Does the endpoint support legacy TLS 1.0 or 1.1?

Each check returns COMPLIANT or NON_COMPLIANT status with specific policy recommendations.

PQC requires endpoints to support TLS 1.3 and use PQC key exchange algorithms. The three-tier framework helps you interpret findings and prioritize fixes. The goal is to have TLS 1.3 with PQC key exchange enabled on the endpoints. However, achieving this requires maintaining backward compatibility with clients.

Tier

Readiness level

TLS protocols

PQC status

Migration priority

Tier 1

PQ-ready (strongest posture)

TLS 1.3 only with PQC key exchange

PQ-ready

None

Tier 2

PQ-ready (backward compatible)

TLS 1.2 and 1.3 with PQC key exchange

PQ-ready

Low

Tier 3

Not PQ-ready

No PQC key exchange

Not PQ-ready

High

How to prioritize your migrations

  • Tier 1 represents the strongest security using only TLS 1.3 with PQC key exchange. These resources already meet the target state.
  • Tier 2 represents a backward-compatible PQ-ready configuration. Endpoints support both TLS 1.2 and TLS 1.3, with PQC key exchange negotiated on TLS 1.3 connections. Migration priority is low because these resources already provide quantum-resistant protection for clients that support TLS 1.3, while maintaining TLS 1.2 compatibility for legacy clients. Migrate to Tier 1 when client-side analysis confirms that the connecting clients support TLS 1.3 with PQC key exchange.
  • Tier 3 covers resources that aren’t PQ-ready. This includes endpoints without TLS 1.3 support, endpoints with TLS 1.3 but without PQC key exchange policies. These resources require immediate attention.

Assessment scope

The scanner evaluates the following AWS edge services that terminate TLS connections on behalf of your applications.

  • Edge services:
    • Application Load Balancer (ALB), Network Load Balancer (NLB) listeners with HTTPS, TLS, and TCP SSL protocols are evaluated.
    • API Gateway REST APIs are evaluated for AWS Regional and private endpoints along with API Gateway HTTP APIs (v2) and WebSocket APIs (v2).
  • Excluded edge services:
    • CloudFront distributions are excluded from the PQC readiness scope because TLS 1.3 with hybrid post-quantum key exchange is automatically enabled across existing CloudFront TLS security policies for viewer-to-edge connections. No customer action is required for inbound (viewer-facing) PQC on CloudFront.
  • Recommended approach for Classic load balancer:
    • For Classic Load Balancers, AWS recommends migrating to ALB or NLB. Classic Load Balancers don’t support TLS 1.3 or PQC key exchange and can’t be made PQ-ready.

How the solution works

AWS Config enables continuous monitoring and evaluation. Conformance packs enable organization-wide deployment. AWS Lambda is a serverless compute service that runs code to perform security policy evaluation based on the AWS Config rules. AWS Serverless Application Model (AWS SAM) is an open source framework used for deploying the AWS Lambda functions.
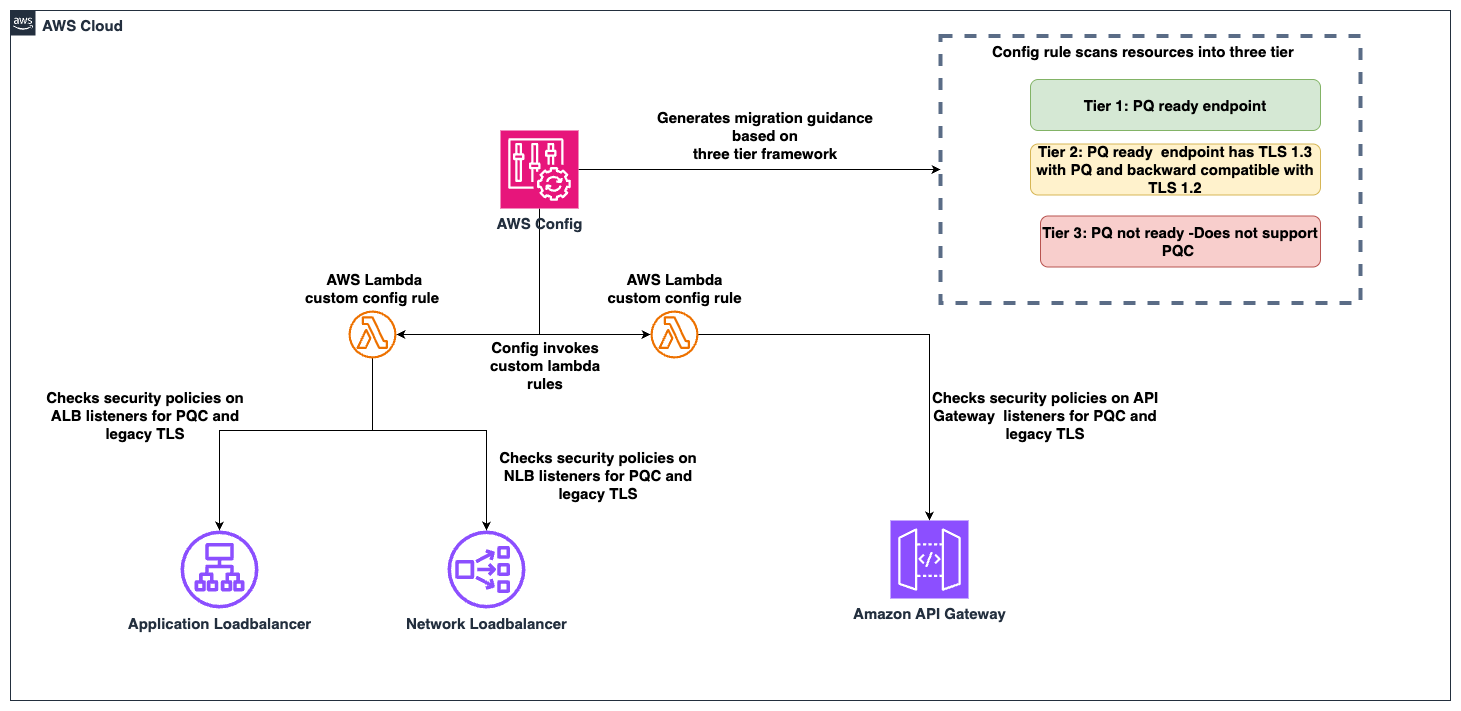
Figure 1: PQC readiness solution architecture

Figure 1: PQC readiness solution architecture

The PQC Readiness Scanner conformance pack implements four custom AWS Config rules powered by two Lambda functions:

Rule

What it checks

Non-compliant result

ELB PQ-ready

Load balancer listeners use security policies that support TLS 1.3 with PQC key exchange algorithms

Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy

ELB legacy TLS

Load balancer listeners allow TLS 1.0 or 1.1 connections

Legacy protocols are configured, the resource is flagged.

API Gateway PQ-ready

API Gateway endpoints use security policies that support TLS 1.3 with PQC key exchange algorithms

Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy

API Gateway legacy TLS

API Gateway endpoints allow TLS 1.0 or 1.1

Legacy protocols are configured, the resource is flagged.

Prerequisites

Before deploying the solution, you need:

  • AWS Command Line Interface (AWS CLI) configured with appropriate permissions
    aws configure
    aws sts get-caller-identity  # Verify

  • Python 3.12 installed. The Lambda runtime requires this version.
    python3 --version  # Should show 3.12.x

  • AWS SAM CLI installed (Installation Guide)
    pip install aws-sam-cli
    
    # Verify
    sam --version

  • AWS Config enabled in your target AWS Region.
    • Configure it to record (This step is not needed if your accounts are recording all resources by default)
      • AWS::ElasticLoadBalancingV2::LoadBalancer
      • AWS::ApiGateway::RestApi
      • AWS::ApiGatewayV2::Api resource types.
    • Enable via AWS Config Console → Recorder → Recording Strategy → Select specific resource types (Follow the steps in manual setup for AWS Config recording strategy for specific resource types)

Steps to deploy the PQC Readiness Scanner

Deploy the PQC Readiness Config Scanner in three phases. Complete deployment commands and configuration details are available in the GitHub repository. The Lambda functions must be deployed first because the conformance pack references their ARNs as parameters. See the GitHub repository for details.

Deploy to single account:

  1. Clone and Build:
    git clone https://github.com/aws-samples/sample-PQC-Readiness-using-AWS-Config.git
    
    cd sample-PQC-Readiness-using-AWS-Config/installation
    
    sam build

  2. Deploy to One or More Regions:
    # Make script executable (first time only)
    chmod +x deploy-per-regions.sh
    
    # Deploy to a single region
    ./deploy-per-regions.sh us-east-1
    
    # Deploy to multiple regions
    ./deploy-per-regions.sh us-east-1 us-west-2 eu-west-1

    Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.

    Figure 2: Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.

  3. The script automatically:
    • Deploys Lambda functions via SAM
    • Deploys conformance pack (creates Config rules)
    • Verifies deployment success
    • Provides clear status messages

The deployment creates two Lambda functions that perform PQ-ready and legacy TLS checks. It provisions IAM roles with least-privilege permissions for ELB, ALB, NLB, and API Gateway describe operations. Lambda permissions allow AWS Config to invoke the functions.
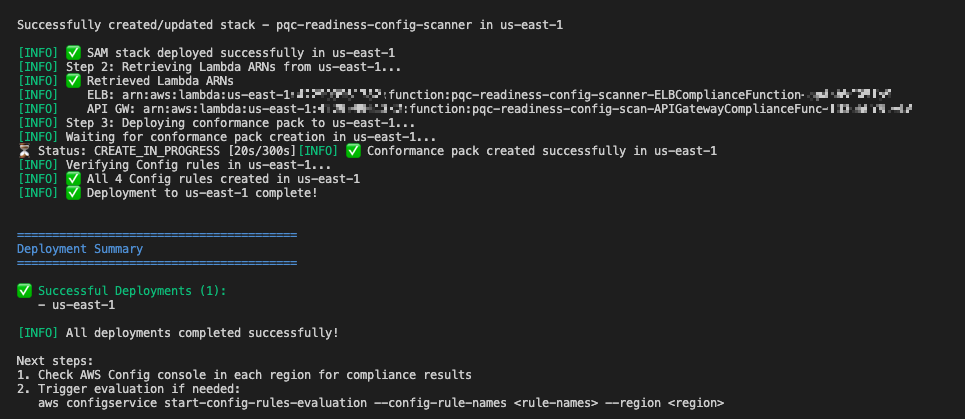
Example screen-print of how a successful deployment looks like.

Figure 3: Example screen-print of what a successful deployment looks like.

Multi-account deployment (Organizations):

For organization-wide deployment across multiple AWS accounts, use CloudFormation StackSets to deploy Lambda functions to each account.

Important Constraint: AWS Config CUSTOM_LAMBDA rules require the Lambda function to exist in the same account as the Config rule. You cannot use a centralized Lambda in one account to evaluate resources in other accounts.

Prerequisite: Shared S3 Bucket

Before packaging, create an S3 bucket accessible by each target account in your organization. This bucket will host the Lambda deployment artifacts that CloudFormation StackSets pulls into each member account.

# Create the shared S3 bucket (run from management/central account)
aws s3 mb s3://<your-org-shared-bucket> --region us-east-1

Grant read access to the target accounts using one of the following options:

aws s3api put-bucket-policy \
  --bucket <your-org-shared-bucket> \
  --policy '{
    "Statement": [
      {
        "Sid": "BucketOwnerFullAccess",
        "Effect": "Allow",
        "Principal": {
          "AWS": "arn:aws:iam::<bucket-owner-account-id>:root"
        },
        "Action": "s3:*",
        "Resource": [
          "arn:aws:s3:::<your-org-shared-bucket>",
          "arn:aws:s3:::<your-org-shared-bucket>/*"
        ]
      },
      {
        "Sid": "CrossAccountReadAccess",
        "Effect": "Allow",
        "Principal": {
          "AWS": [
            "arn:aws:iam::<account-id-1>:root",
            "arn:aws:iam::<account-id-2>:root"
          ]
        },
        "Action": ["s3:GetObject", "s3:ListBucket"],
        "Resource": [
          "arn:aws:s3:::<your-org-shared-bucket>",
          "arn:aws:s3:::<your-org-shared-bucket>/*"
        ]
      }
    ]
  }'

Replace <account IDs> with the AWS account IDs where StackSets will deploy the Lambda functions.

Note: The bucket must be in the same region as the StackSet deployment regions. For multi-region deployments, create one bucket per region and run sam package separately for each.

Step 1: Build and Upload Lambda Packages to S3

Run the packaging script from the installation/ directory:

cd installation

# Make script executable (first time only)
chmod +x deploy-stacksets.sh

# Build, package, upload to S3, and generate resolved template
./deploy-stacksets.sh <your-org-shared-bucket>

This script automatically:

  • Builds Lambda functions using SAM
  • Creates ZIP packages
  • Uploads ZIPs to the shared S3 bucket
  • Generates packaged-template.yaml with S3 values baked in (no parameters needed at deploy time)
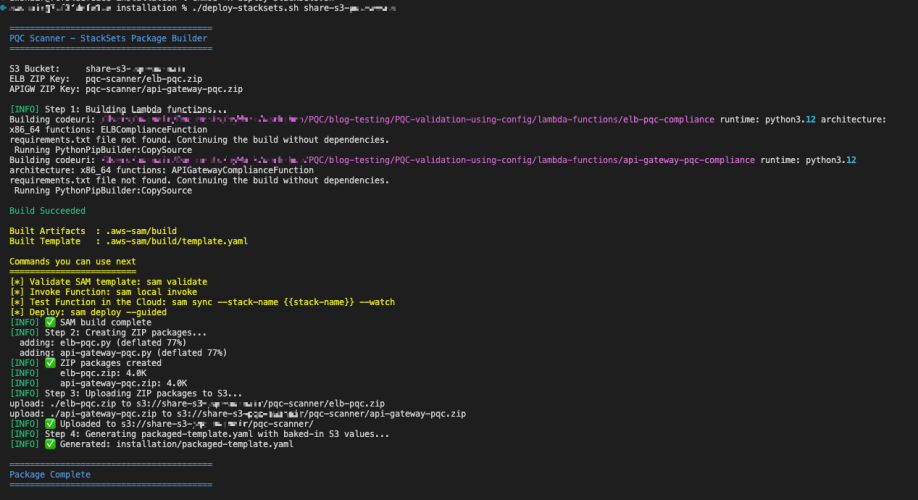
Sample script output of successful upload of the lambda packages to S3 bucket

Figure 4: Sample script output of successful upload of the lambda packages to S3 bucket

Step 2: Deploy Lambda Functions via StackSets

Run the following from the management account (or delegated admin account):

# Create StackSet (--region sets the StackSet "home region" where it is managed)
aws cloudformation create-stack-set \
  --stack-set-name pqc-readiness-lambda-functions \
  --template-body file://packaged-template.yaml \
  --capabilities CAPABILITY_IAM \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=false \
  --region us-east-1

# Deploy stack instances to member accounts
# --regions = target regions where Lambda functions are deployed in member accounts
# --region  = must match the StackSet home region above
aws cloudformation create-stack-instances \
  --stack-set-name pqc-readiness-lambda-functions \
  --deployment-targets OrganizationalUnitIds=ou-xxxx-xxxxxxxx \
  --regions us-east-1 \
  --region us-east-1

Important — StackSet home region vs deployment regions:

  • --region (on each CLI command) = the StackSet home region where the StackSet resource lives. Subsequent operations (describe, update, delete) must specify this same region.
  • --regions (on create-stack-instances) = the deployment target region(s) where stack instances are created in member accounts.
  • These are independent values. Specify --region explicitly to avoid accidental deployment to your CLI’s default region.

Note: SERVICE_MANAGED StackSets must be created from the management or delegated admin account. The management account itself is excluded from stack instance deployments — use deploy-per-regions.sh separately if you need the scanner in the management account.

Step 3: Deploy Organization Conformance Pack

aws configservice put-organization-conformance-pack \
  --organization-conformance-pack-name pqc-legacy-tls-compliance \
  --template-body file://conformance-packs/pqc-legacy-tls-conformance-pack.yaml

This creates Config rules in each member account that reference their local Lambda functions.

    Migration guidance and prioritization

    The three-tier system provides PQC migration priorities:

    High priority – Tier 3 (not PQ-ready):

    • Target: Resources without PQC support. This includes endpoints not using PQ-ready security policies, endpoints that still allow TLS 1.0 or 1.1.
    • Action: Upgrade to a PQ-ready policy containing PQ in its name, such as those ending with -PQ-2025-09 (see Elastic Load Balancing security policies documentation for the full list).
    • Important: Before upgrading to a PQ-ready policy, audit your client TLS versions. PQ-ready policies require TLS 1.3 support; legacy clients that only support TLS 1.2 or earlier will fail to negotiate a connection. Start with a Tier 2 backward-compatible policy (which supports both TLS 1.2 and 1.3 with PQC), monitor connection logs for TLS negotiation failures, and only move to a Tier 1 TLS 1.3-only policy after confirming that your clients support TLS 1.3 with PQC key exchange.
    • Risk: Endpoints don’t support post-quantum cryptography for data in transit. Legacy TLS protocols are vulnerable to current cryptographic attacks.

    Low priority – Tier 2 (PQ-ready, backward compatible):

    • Target: Resources using TLS 1.3 + PQ-ready policies that also support TLS 1.2 for backward compatibility.
    • Action: Consider TLS 1.3-only policies when client compatibility analysis confirms connecting clients support TLS 1.3.
    • Risk: Minimal. These resources already support PQ-TLS with TLS 1.3 connections. TLS 1.2 and earlier fallback maintains backward compatibility, which might indicate some clients aren’t negotiating in PQ-TLS. Remediation is to monitor logs, identify the volume of these connections and clients and plan migration for these clients to use TLS 1.3 with PQ-TLS.

    No action – Tier 1 (PQ-ready, optimal):

    • Target: Resources using TLS 1.3 only with PQC key exchange: These resources meet the target state. No migration needed.

    Viewing the results

    In each member account, navigate to AWS Config Console in the deployed region.

    Conformance Pack View

    Go to AWS Config → Conformance packs and look for:

    OrgConformsPack-pqc-legacy-tls-compliance-

    Note: Organization conformance packs are prefixed with OrgConformsPack- and have a random suffix appended (e.g., OrgConformsPack-pqc-legacy-tls-compliance-gyv22je0).
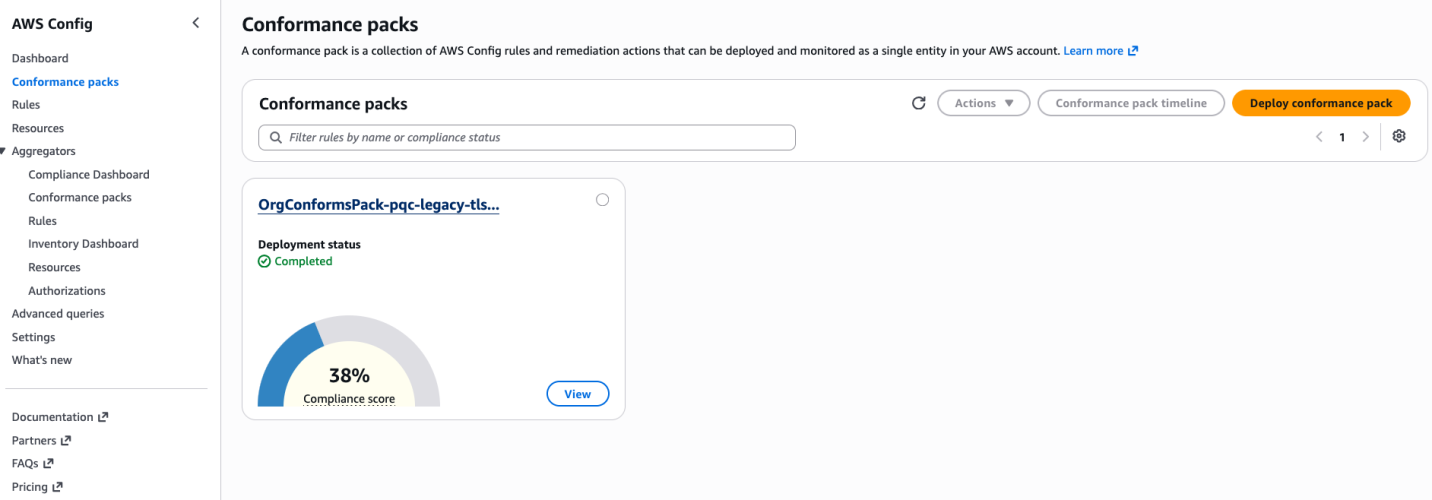
    PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource

    Figure 5: PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource

    Click the conformance pack to see an overall compliance summary across all 4 rules.

    Individual Rules View

    Go to AWS Config → Rules and find 4 rules with prefix pqc-:

    • pqc-elb-pqc-compliance-conformance-pack-
    • pqc-elb-legacy-tls-conformance-pack-
    • pqc-apigateway-pqc-compliance-conformance-pack-
    • pqc-apigateway-legacy-tls-conformance-pack-

    Click any rule to view:

    • Compliant vs non-compliant resource counts
    • Detailed annotations for each resource
    • Resource ARNs and current security policy configurations
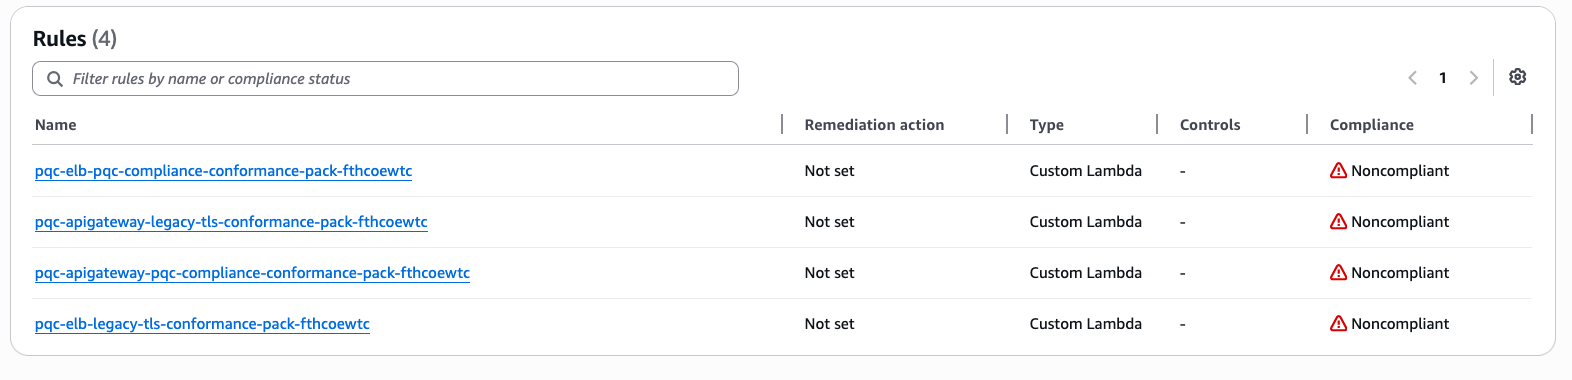
    Visibility into Config rules status inside the conformance pack
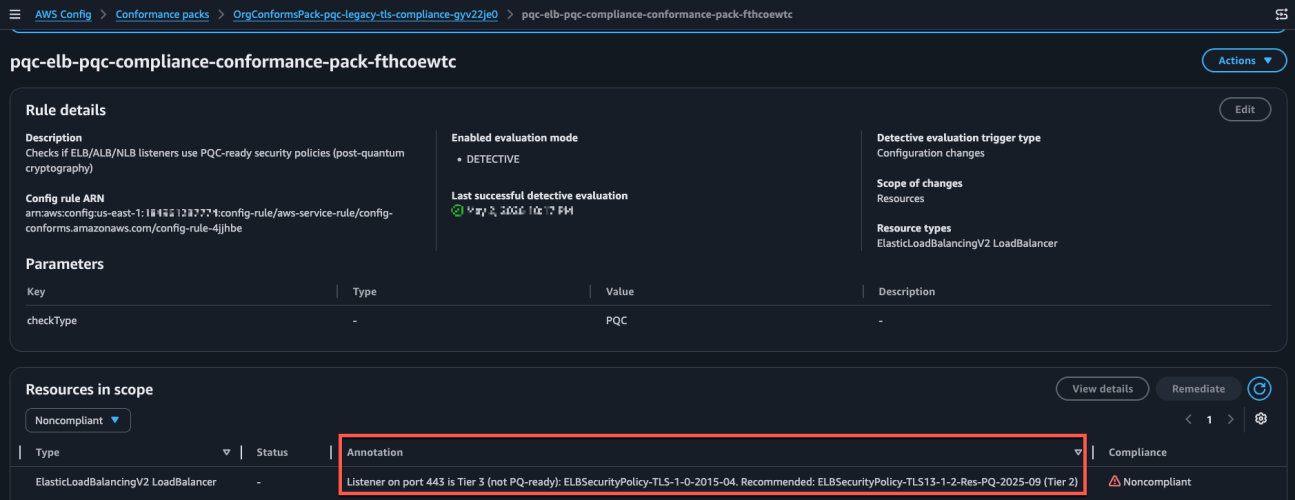
    Figure 6: Visibility into Config rules status inside the conformance pack

    Sample image of the config rule findings and annotation describing the migeration guidance based on 3-tier classification.

    Figure 7: Sample image of the config rule findings and annotation describing the migration guidance based on 3-tier classification.

    Conclusion

    After deploying the PQC Readiness Scanner, you gain visibility into TLS posture across AWS edge services, which reduces manual configuration reviews. The tier system provides specific upgrade recommendations so teams can understand next steps without cryptographic expertise. The scanner automatically detects configuration changes to help new deployments maintain readiness standards. Built-in AWS Config reporting supports audit requirements and demonstrates measurable progress toward PQC readiness.

    Deploy the PQC Readiness Scanner and review your results with PQC Readiness Scanner. Start migration with high priority Tier 3 resources and monitor progress across your accounts using AWS Config aggregators.

    Additional resources

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS Config re:Post or contact AWS Support.
    Pravin Nair

    Pravin Nair

    Pravin is a Senior Security Solutions Architect specializing in data protection and privacy at AWS. He partners with customers to architect secure, scalable cloud solutions that address complex security challenges across encryption, infrastructure protection, and privacy engineering. His expertise spans encryption at rest and in transit, infrastructure security, privacy-based architectures, and emerging security domains including generative AI security and post-quantum cryptography.

    Building hybrid multi-tenant architecture for stateful services on AWS

    Post Syndicated from Vasu Raj original https://aws.amazon.com/blogs/architecture/building-hybrid-multi-tenant-architecture-for-stateful-services-on-aws/

    Running a large-scale ad-serving infrastructure presents unique challenges when balancing tenant isolation with operational efficiency. Our infrastructure handles millions of requests per second and generates billions of dollars in annual advertising revenue, serving ads across multiple properties and systems.

    The cellular architecture problem

    Earlier, we had a cellular architecture where we allocated each AWS account with Application Load Balancer (ALB) and Amazon Elastic Container Service (Amazon ECS) to a given tenant. This approach provided accurate isolation but created the following significant operational challenges.

    • The scale problem: Supporting only 18 clients across four AWS Regions requires 181 separate targets. Our team configured dedicated AWS accounts, VPCs, load balancers, AWS Identity and Access Management (IAM) roles, and downstream service connections for each client.
    • The efficiency problem: Our servers spent more than 98 percent of their time waiting and less than 1 percent executing code. Average CPU utilization sat at 3 percent, and memory at 19 percent. We were paying for massive infrastructure that remained idle most of the time.
    • The onboarding problem: Bringing a new client online took approximately 52 days—roughly two weeks for AWS account provisioning, three weeks for VPC and networking setup, one week for IAM role configuration, and two weeks for downstream service integration and testing.
    • The scalability problem: When traffic grows or a new client joined, our only option is to spin up an entirely new cell and migrate to the client. We couldn’t support concurrent tier-1 live events—multiple high-value games couldn’t run simultaneously, forcing us to divert traffic to alternative systems.
    • The noisy neighbor problem: Despite our isolation efforts, we still experienced performance degradation when tenants shared infrastructure, affecting service quality and reliability.

    Why we needed dedicated compute

    Our ad-serving platform is a stateful service that loads and maintains data in memory for each tenant rather than fetching it from a database on every request. This in-memory state improves performance but creates the noisy neighbor problem when tenants share infrastructure.When two tenants share a cluster, their in-memory data competes for the same heap. A tenant with a large dataset can trigger out-of-memory conditions that affect its neighbors. This made shared-task and shared-cluster approaches challenging our stateful workloads.We needed a solution that maintained cluster-level isolation while dramatically improving operational efficiency.

    Solution overview

    We designed a hybrid multi-tenant architecture that provides cluster-level isolation within shared accounts. Here’s what we implemented:

    • Pre-integration model: Instead of provisioning VPCs, IAM roles, and downstream service connections for each new tenant, we created a configuration-driven infrastructure where these integrations are established once and reused across tenants.
    • Amazon Route 53 weighted routing: We implemented Route 53 weighted routing to enable gradual traffic migration between clusters without client-side changes. This allowed us to shift tenants between tiers as their traffic patterns evolved.
    • AWS PrivateLink connectivity: We established AWS PrivateLink endpoints that all tenants share, removing the need for us to set up new VPC peering or Transit Gateway connections for each tenant and reducing network configuration overhead by 80 percent.
    • Tier-based architecture: We organized our infrastructure into tiers (High TPS, Standard TPS, Low TPS) with multiple cells per tier, enabling horizontal scaling without the operational burden of per-tenant AWS accounts.
    • Configuration-driven onboarding: New tenant onboarding became a configuration change rather than an infrastructure provisioning exercise, dramatically reducing time and manual effort.

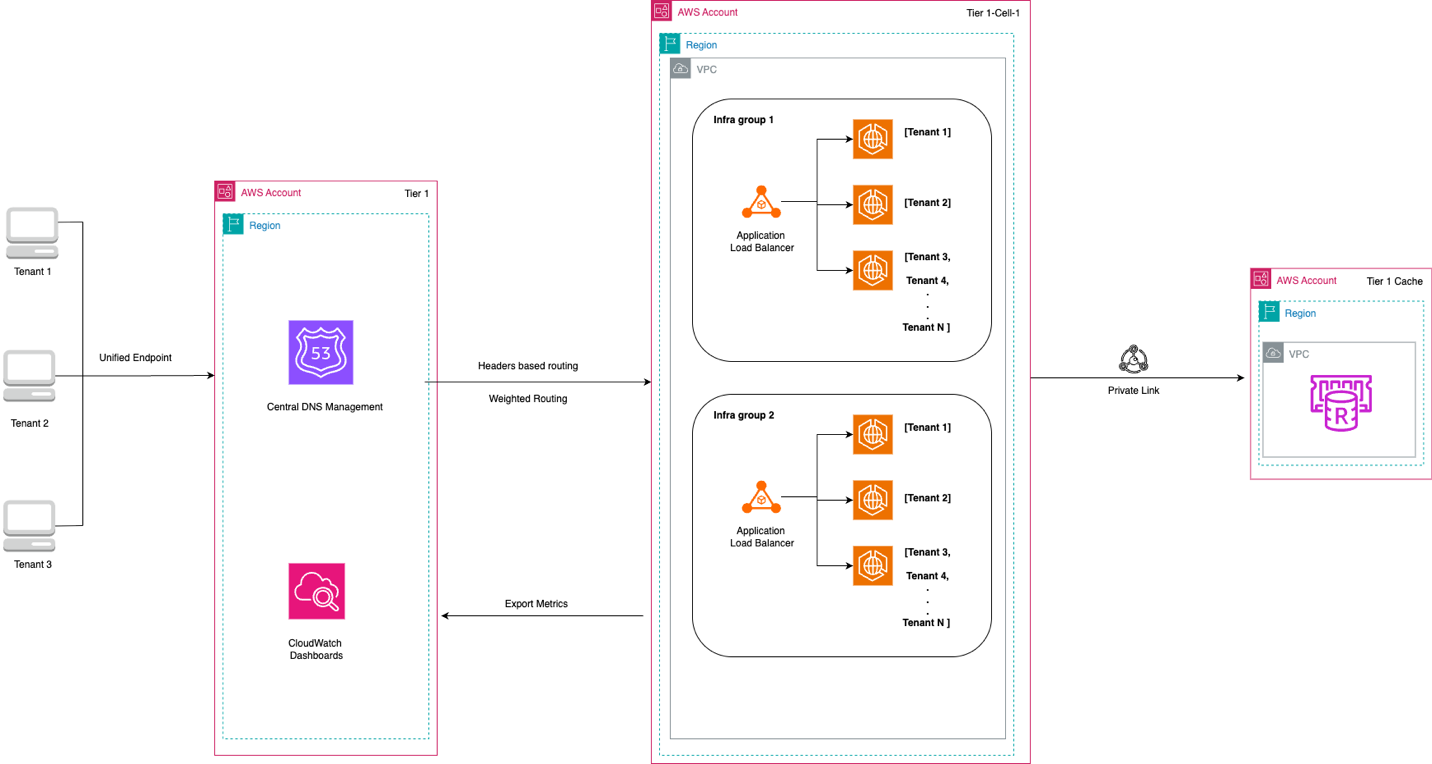
    The architecture is organized around three nested levels of hierarchy. A tier is the top-level grouping—a logical classification of tenants that share a common infrastructure footprint. A tier spans one or more cells, where each cell is an AWS account boundary that represents the unit of horizontal scale-out at the account level. Within each cell, one or more infra groups serve as the self-contained infrastructure unit: a VPC, an Application Load Balancer, a set of ECS clusters (one per tenant), IAM roles, and a monitoring stack.

    Why three levels? As you scale from 10 to 100 to 1,000 tenants, you will reach different AWS limits at different scales. Application Load Balancer target group limits constrain how many tenants fit in a single load balancer. AWS account limits on Elastic Network Interfaces (ENIs) and VPC endpoints constrain how many load balancers fit in a single account. This three-level hierarchy gives you two independent scaling levers to address each constraint—add infra groups to scale within an account and add cells to scale across accounts. The key design principle is that we pre-wire downstream service dependencies at tier creation, not at tenant onboarding. AWS PrivateLink connections from the tier VPC to each downstream service VPC are established after the tier is provisioned. After onboarding tenants to that tier, they automatically inherit full downstream connectivity. This single architectural decision is the primary reason for the 80 percent reduction in infrastructure setup steps. Route 53 performs weighted DNS routing across Application Load Balancers in multiple infra groups and cell accounts, enabling horizontal scale-out without client-side changes.

    The following diagram illustrates the full architecture: Route 53 distributes traffic across ALBs in multiple infra groups within a single cell account, each ALB routes to tenant-specific ECS clusters using listener rules and target groups, and the clusters share tier-level PrivateLink connections to downstream services.

    Multi-Tenant Architecture Diagram

    Figure 1: Hybrid multi-tenant architecture showing Route 53 weighted routing, Application Load Balancer listener rules, dedicated ECS clusters per tenant, and shared AWS PrivateLink connections to downstream services.

    Prerequisites

    Before you build this architecture, make sure that you have the following:An AWS account configured with least privileged permissions to create VPCs, Application Load Balancers, ECS clusters, Route 53 hosted zones, and VPC endpoints. You also need the AWS Command Line Interface (AWS CLI) version 2.x or later installed and configured with appropriate credentials. This walkthrough assumes intermediate familiarity with Amazon ECS, Application Load Balancer, and Amazon Route 53—specifically ECS task definitions, Application Load Balancer listener rules, and Route 53 routing policies. You also need at least one downstream service exposing a VPC endpoint service for AWS PrivateLink connectivity.

    Estimated time to complete: 2–3 hours.

    Walkthrough

    This walkthrough shows you how to build the previously described hybrid multi-tenant architecture. You will configure Route 53 weighted routing, deploy an ALB with tenant-specific listener rules, create dedicated ECS clusters per tenant, and establish AWS PrivateLink connectivity to shared downstream services. These will be done in a way that makes future tenant onboarding a configuration-only operation.

    Step 1: Configure Route 53 Regional endpoints with weighted routing

    Each tier exposes a single Regional DNS endpoint (for example, tier-1.us-east-1.example.com) backed by Route 53 weighted routing records. You can configure Route 53 to use weighted routing to help distribute traffic across ALBs in multiple AWS accounts. When you add a new account to the tier for horizontal scale-out, add a new weighted record. You don’t need to change existing tenant DNS entries.

    To configure Route 53 weighted routing for a tier:

    1. Open the Amazon Route 53 console and choose Hosted zones.
    2. Select or create the hosted zone for your tier.
    3. Choose Create record and select Weighted as the routing policy.
    4. Set the record name to your tier endpoint (for example, tier-1.us-east-1.example.com), record type to A, and configure an alias pointing to the ALB in your first AWS account.
    5. Set the Weight to 50 and provide a unique Set ID (for example, account-1).
    6. Enable Evaluate target health so Route 53 helps make sure that it directs traffic to healthy ALBs when you configure health evaluation.
    7. Repeat for each additional AWS account in the tier, using matching weights.

    Alternatively, run the following AWS CLI command to create the first weighted record:

    aws route53 change-resource-record-sets \
      --hosted-zone-id YOUR_HOSTED_ZONE_ID \
      --change-batch '{
        "Changes": [{
          "Action": "CREATE",
          "ResourceRecordSet": {
            "Name": "tier-1.us-east-1.example.com",
            "Type": "A",
            "SetIdentifier": "account-1",
            "Weight": 50,
            "AliasTarget": {
              "HostedZoneId": "Z35S*****K",
              "DNSName": "your-alb.us-east-1.elb.amazonaws.com",
              "EvaluateTargetHealth": true
            }
          }
        }]
      }'

    Note: Replace Z35S****K with the hosted zone ID for your ALB’s AWS Region. For more information, see Elastic Load Balancing endpoints and quotas.

    Route 53 supports up to 10,000 weighted records per hosted zone, so this approach scales to thousands of AWS accounts without architectural changes. For more information about weighted routing, see Weighted routing in the Amazon Route 53 Developer Guide.

    Step 2: Deploy an Application Load Balancer with tenant-specific listener rules

    Each infra group contains one Application Load Balancer. The load balancer inspects incoming requests and forwards them to the correct tenant’s ECS service based on a tenant identifier extracted from the request path or a custom HTTP header.

    Two Application Load Balancer quotas shape the capacity of each infra group: a maximum of 100 target groups per load balancer, and a maximum of 5 target groups per listener rule. With 20 listener rules each forwarding to 5 target groups, a single load balancer supports up to 50 tenants per infra group. With up to 5 ECS clusters per tenant, a single infra group can host up to 100 ECS clusters.

    To create a tenant-specific listener rule:

    1. Open the Amazon EC2 console and choose Load Balancers in the navigation pane.
    2. Select your Application Load Balancer and choose the Listeners tab.
    3. Choose View/edit rules for the HTTPS listener.
    4. Choose the plus (+) icon to add a new rule.
    5. Add a condition: Path is /tenant-a/* (or HTTP header if you use header-based routing).
    6. Add an action: Forward to the target group for tenant-a.
    7. Set a unique rule priority and save.

    To create the target group and listener rule using the AWS CLI:

    # Create a target group for the tenant
    aws elbv2 create-target-group \
      --name tg-tenant-a \
      --protocol HTTP --port 8080 \
      --vpc-id YOUR_VPC_ID \
      --target-type ip
    # Add a listener rule routing /tenant-a/* to the target group
    aws elbv2 create-rule \
      --listener-arn YOUR_LISTENER_ARN \
      --conditions '[{"Field":"path-pattern","Values":["/tenant-a/*"]}]' \
      --actions '[{"Type":"forward","TargetGroupArn":"YOUR_TARGET_GROUP_ARN"}]' \
      --priority 10

    For more information, see Listener rules for your Application Load Balancer.

    Step 3: Create dedicated ECS clusters per tenant

    In this step, you create a dedicated ECS cluster for each tenant within your infra group’s VPC. Use a consistent naming convention that encodes the tier, cell, infra group, and tenant identifier (for example, tier-1-cell-1-ig-1-tenant-a) to make ownership clear during operations and incident response.To create a dedicated ECS cluster for a tenant:

    1. Open the Amazon ECS console and choose Clusters.
    2. Choose Create cluster.
    3. Enter a cluster name following your naming convention (for example, tier-1-cell-1-ig-1-tenant-a).
    4. Select EC2 Linux + Networking and configure the instance type and Auto Scaling group settings appropriate for the tenant’s workload.
    5. Select the infra group VPC and subnets.
    6. Choose Create.

    To create the cluster using the AWS CLI:

    aws ecs create-cluster \
      --cluster-name tier-1-cell-1-ig-1-tenant-a \
      --region us-east-1

    In the ECS task definition for this tenant, pass the tenant identifier as an environment variable. The application reads this value at startup to scope its data access — loading only that tenant’s configuration and state from the shared remote cache:

    {
      "containerDefinitions": [{
        "name": "app",
        "image": "your-ecr-image:latest",
        "environment": [
          { "name": "TENANT_ID", "value": "tenant-a" },
          { "name": "CACHE_ENDPOINT", "value": "cache.tier-1.internal" }
        ]
      }]
    }

    Note: Replace your-ecr-image:latest with your Amazon Elastic Container Registry (Amazon ECR) image URI.

    Register the ECS service as a target in the ALB target group created in Step 2. Configure ECS service auto-scaling based on central processing unit (CPU) and memory utilization metrics, scoped to the individual service. Because each cluster is single-tenant, the ECS limit of 5,000 tasks per service applies exclusively to that tenant. One tenant’s resource consumption can’t affect another tenant’s cluster. For more information, see Creating a cluster in the Amazon ECS Developer Guide.

    Step 4: Establish AWS Private Link connectivity to shared dependencies

    This step happens at tier creation, not at tenant onboarding—and that distinction is the architectural heart of the design. For each downstream service your application integrates with, create a VPC interface endpoint in the infra group VPC. The ECS tasks in the tier route traffic to downstream services through these endpoints. Tenants onboarded to that tier can access downstream connectivity through the pre-configured endpoints.

    Each VPC interface endpoint costs approximately $7.30/month plus data transfer charges ($0.01/GB). For a tier with 50 tenants sharing one endpoint, this cost is negligible compared to the operational savings. If your downstream services are in the same VPC, consider using VPC peering or AWS Transit Gateway as lower-cost alternatives. Use AWS PrivateLink when you need to connect to services in different AWS accounts or when you require the security and isolation benefits of private connectivity.

    To create a VPC interface endpoint for a downstream service:

    1. Open the Amazon VPC console and choose Endpoints in the navigation pane.
    2. Choose Create endpoint.
    3. Select Find service by name and enter the VPC endpoint service name provided by the downstream service owner.
    4. Select the infra group VPC and the subnets used by ECS tasks.
    5. Attach a security group that allows outbound traffic from ECS tasks to the endpoint on the required port.
    6. Choose Create endpoint.

    To create the endpoint using the AWS CLI:

    aws ec2 create-vpc-endpoint \
      --vpc-id YOUR_VPC_ID \
      --service-name com.amazonaws.vpce.us-east-1.vpce-svc-YOUR_SERVICE_ID \
      --vpc-endpoint-type Interface \
      --subnet-ids subnet-*** subnet-*** \
      --security-group-ids sg-YOUR_SG_ID

    Define tier-level IAM roles with the permissions needed to access downstream services and assign these roles to ECS task definitions at the tier level. New tenants can receive the tier-level permissions through the shared IAM roles without per-tenant role creation. For more information, see Access an AWS service using an interface VPC endpoint.

    Step 5: Configure tenant isolation, scaling, and observability

    This architecture enforces tenant isolation at three layers through customer configuration. At the routing layer, ALB listener rules route traffic exclusively to the correct tenant’s target group based on the tenant identifier. ALB listener rules help route traffic to the correct tenant’s target group based on your configuration. At the compute layer, each tenant has a dedicated ECS cluster, so resource limits apply per cluster and cluster-level isolation is designed to help minimize the impact of one tenant’s resource consumption on another tenant. At the in-memory state layer, because each ECS cluster is single-tenant, in-memory data loaded at startup belongs exclusively to that tenant with no shared heap between tenants.

    Scaling strategies

    When a single tenant’s traffic grows but you haven’t reached the 50-tenant limit per infra group, use vertical scaling — it’s faster (minutes vs. hours) and doesn’t require Route 53 changes. Increase ECS task CPU and memory reservations in the task definition, or switch to larger EC2 instance types in the Auto Scaling group.

    When you’re approaching the 50-tenant limit or when multiple tenants need capacity simultaneously, add a new infra group within the same cell—a new VPC, ALB, and set of ECS clusters. Route 53 weighted routing distributes traffic across infra groups without client-side changes:

    aws route53 change-resource-record-sets \
      --hosted-zone-id YOUR_HOSTED_ZONE_ID \
      --change-batch '{
        "Changes": [{
          "Action": "CREATE",
          "ResourceRecordSet": {
            "Name": "tier-1.us-east-1.example.com",
            "Type": "A",
            "SetIdentifier": "cell-1-ig-2",
            "Weight": 50,
            "AliasTarget": {
              "HostedZoneId": "Z3******K",
              "DNSName": "your-alb-ig-2.us-east-1.elb.amazonaws.com",
              "EvaluateTargetHealth": true
            }
          }
        }]
      }'

    Use cell-level scaling only when you’re approaching account-level limits—typically after 3–4 infra groups per cell. Each AWS account has hard limits on ENIs, VPC endpoints, and other resources. When a cell approaches these limits, add a new cell by provisioning an identical tier infrastructure stack in a new AWS account and registering its ALBs in Route 53 with weighted records alongside existing cells:

    aws route53 change-resource-record-sets \
      --hosted-zone-id YOUR_HOSTED_ZONE_ID \
      --change-batch '{
        "Changes": [{
          "Action": "CREATE",
          "ResourceRecordSet": {
            "Name": "tier-1.us-east-1.example.com",
            "Type": "A",
            "SetIdentifier": "cell-2",
            "Weight": 50,
            "AliasTarget": {
              "HostedZoneId": "Z35SXDOTRQ7X7K",
              "DNSName": "your-alb-cell-2.us-east-1.elb.amazonaws.com",
              "EvaluateTargetHealth": true
            }
          }
        }]
      }'

    The tier endpoint (tier-1.us-east-1.example.com) remains stable. Tenants don’t need to update their DNS configuration as the tier grows. The following table summarizes when to use each scaling lever:

    Trigger Action Unit added
    Application Load Balancer target group limit (~50 tenants per infra group) Add an infra group within the same cell Infra group (VPC + Application Load Balancer + ECS clusters)
    AWS account-level limits (ENIs, VPC endpoints) Add a new cell Cell (new AWS account)

    Observability

    Observability is structured at two levels. Emit tenant-level metrics from each ECS service with the tenant identifier as an Amazon CloudWatch dimension. Key metrics to monitor:

    Memory usage per ECS service is the primary signal for in-memory state growth. A sudden spike often indicates a data model change or misconfigured data pipeline. Set CloudWatch alarms at 70 percent (warning) and 85 percent (critical). When memory usage exceeds 70 percent, investigate whether the tenant’s data model has changed or if a data pipeline is misconfigured. At 85 percent, prepare to vertically scale the ECS task definition. TargetResponseTime and request count per ALB target group measure latency and throughput per tenant. Establish a baseline for each tenant during onboarding (typically 100–200 ms for stateful services), then alert when latency exceeds 2x baseline for more than 5 minutes. HTTPCode_Target_5XX_Count per target group tracks error rate per tenant.For tier-level health, monitor ALB ActiveConnectionCount and ProcessedBytes, Route 53 health check status per load balancer, and ECS cluster CPU reservation and memory reservation for capacity planning. Configure Amazon CloudWatch Logs with structured log fields including tenant_id, tier_id, and region in every log entry. Use a single log group per tier with log stream prefixes that encode the tenant identifier. The following CloudWatch Logs Insights query identifies error rates by tenant across the entire tier:

    fields @timestamp, tenant_id, @message
    | filter @message like /ERROR/
    | stats count() as error_count by tenant_id
    | sort error_count desc

    Step 6: Validate the architecture

    Before onboarding production tenants, validate your architecture with the following checks:

    1. Send test requests to your tier endpoint with different tenant identifiers in the path.
    2. Verify that Route 53 distributes traffic across Application Load Balancers: aws route53 test-dns-answer --hosted-zone-id YOUR_ID --record-name tier-1.us-east-1.example.com
    3. Confirm the load balancer routes requests to the correct tenant’s ECS cluster by checking ALB access logs.
    4. Test AWS PrivateLink connectivity by making requests from ECS tasks to downstream services.
    5. Simulate a tenant memory spike by loading a large dataset and confirm that it doesn’t affect other tenants.
    6. Verify that CloudWatch metrics are being emitted with correct tenant_id dimensions.

    Results

    These results come from implementing this architecture for a stateful ad-serving application. Before this architecture, onboarding a new tenant required 52 days. With this architecture, onboarding dropped to seven days—primarily testing and validation, because infrastructure is pre-provisioned.

    Measured improvements:

    • Tenant onboarding time: from 52 days to 7 days (86 percent reduction)
    • Infrastructure setup steps per tenant: 80 percent fewer
    • Engineering effort per onboarding: 80 percent reduction
    • Feature release time: from 2–3 days to 1 day
    • Tenant capacity: up to 100 tenants per AWS account with strong cluster-level isolation

    Cleaning up

    To avoid incurring future charges, delete the resources in the following order:

    1. Deregister ECS services from target groups, then delete ECS clusters (this might take 5–10 minutes).
    2. Delete Application Load Balancer listener rules, then delete target groups associated with test tenants.
    3. Remove Route 53 weighted routing records for test tier endpoints.
    4. Delete VPC interface endpoints (AWS PrivateLink) created during tier setup.
    5. Terminate EC2 instances in Auto Scaling groups, then delete the Auto Scaling groups.
    6. (Optional) Delete the VPC if no other resources depend on it.

    Note: Deleting these resources stops charges immediately. If you plan to reuse this architecture, consider stopping ECS services instead of deleting clusters.

    Conclusion

    In this post, I showed you how to build a hybrid multi-tenant architecture that provides strong tenant isolation without requiring per-tenant AWS accounts. You learned how to configure Route 53 weighted routing to distribute traffic across multiple accounts, deploy Application Load Balancer listener rules for tenant-specific routing, create dedicated ECS clusters per tenant, and establish AWS PrivateLink connectivity to shared dependencies. This approach reduced tenant onboarding time by 86 percent and infrastructure setup steps by 80 percent.

    The most important design decision is decoupling dependency setup from tenant onboarding. Pre-wiring the PrivateLink connections, IAM roles, and remote cache endpoints at tier creation transforms onboarding from a multi-week infrastructure project into a configuration-only operation. The three-level hierarchy (tier, cell, infra group) gives you two independent scaling levers. Add infra groups when an Application Load Balancer approaches its target group limit. Add cells when an AWS account approaches its ENI or VPC endpoint limits. Route 53 weighted routing absorbs both changes transparently.

    Next steps

    Ready to implement this architecture? Here’s how to get started:

    1. Assess your current tenant distribution and identify candidates for tier consolidation.
    2. Define tier promotion criteria based on your latency and isolation requirements.
    3. Start with a single tier and 2–3 test tenants to validate the architecture.
    4. Gradually migrate existing tenants using a phased approach.
    5. Monitor tenant-level metrics for 2–4 weeks before scaling to additional tiers.

    For additional guidance, review the AWS Well-Architected Framework — SaaS Lens and explore the SaaS ECS reference architecture on the GitHub website.

    Optional enhancements

    After you’ve implemented this architecture, consider these additional improvements: formalized tier migration playbooks with automated tooling to make moving tenants between tiers a predictable, low-risk operation; and bin-packing analysis across tiers to identify tenants whose memory footprints allow co-location on the same EC2 instance without sharing a cluster, reducing EC2 costs while maintaining isolation properties.Have you implemented a similar multi-tenant architecture? Leave a comment or reach out to share your story.

    Related resources


    About the authors

    Secure multi-warehouse Amazon Redshift access behind a Network Load Balancer using Microsoft Entra ID

    Post Syndicated from Raghu Kuppala original https://aws.amazon.com/blogs/big-data/secure-multi-warehouse-amazon-redshift-access-behind-a-network-load-balancer-using-microsoft-entra-id/

    As data analytics workloads scale, organizations face two challenges. First, they must deliver high-performance analytics at massive scale while maintaining secure access across diverse tools. Second, they must manage high-concurrency workloads while integrating with existing identity management systems.

    You can address these challenges by using Amazon Redshift Serverless endpoints behind an AWS Network Load Balancer with Microsoft Entra ID federation. This architecture can authenticate while helping to streamline identity management across your data environment. Amazon Redshift Serverless provides petabyte-scale analytics with auto scaling capabilities, enabling high-concurrency workloads while streamlining user authentication and authorization.

    In this post, we show you how to configure a native identity provider (IdP) federation for Amazon Redshift Serverless using Network Load Balancer. You will learn how to enable secure connections from tools like DBeaver and Power BI while maintaining your enterprise security standards.

    Solution overview

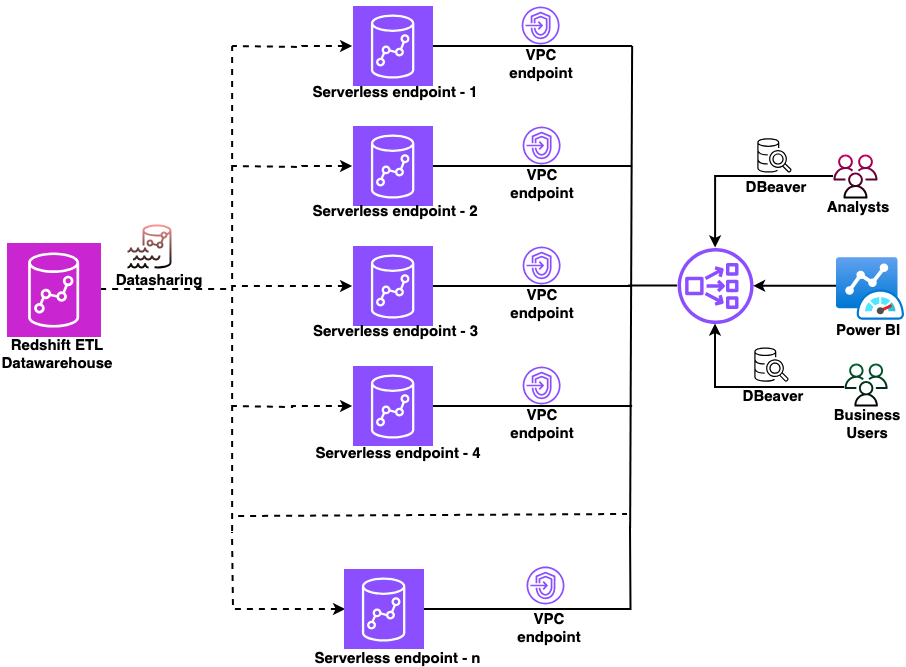
    The following diagram shows the architecture.

    Figure 1: Sample architecture diagram

    Figure 1: Sample architecture diagram

    In this architecture:

    • A central Amazon Redshift ETL data warehouse shares data to multiple Amazon Redshift Serverless workgroups using Amazon Redshift data sharing.
    • Each workgroup has a dedicated managed Amazon Virtual Private Cloud (Amazon VPC) endpoint.
    • A Network Load Balancer sits in front of all VPC endpoints, providing a single connection point.
    • Users connect from DBeaver or Power BI through the Network Load Balancer and authenticate using their Microsoft Entra ID credentials.

    This setup works whether you’re validating the concept with a single workgroup today or planning to scale to multiple workgroups in the future.

    Prerequisites

    Before you begin, make sure that you have completed these prerequisites.

    1. Create Amazon Redshift Serverless endpoints.
    2. Set up datashare from producer to Amazon Redshift Serverless endpoints.
    3. Create Amazon Redshift-managed VPC endpoints.
    4. Create a Network Load Balancer.
    5. Configure a domain name.
    6. Set up Amazon Redshift native IdP federation with Microsoft Entra ID.
    7. Gather the following from your registered application in Microsoft Entra ID:
      1. Scope (API-Scope)
      2. Azure Client ID (AppID from App Registration Details)
      3. IdP Tenant (Tenant ID from App Registration Details)
    8. Download and install the latest Amazon Redshift JDBC and ODBC drivers.

    This solution uses the following AWS services.

    Implementation steps

    This section covers configuring the Network Load Balancer, setting up an ACM certificate, creating custom domain names in Amazon Redshift, configuring DNS records in Amazon Route 53, and connecting your JDBC and ODBC clients using Microsoft Entra ID authentication.

    1. Configure the Network Load Balancer

    First, collect the private IP addresses for your Amazon Redshift-managed VPC endpoints:

    1. Open the Amazon Redshift Serverless console.
    2. Choose your workgroup.
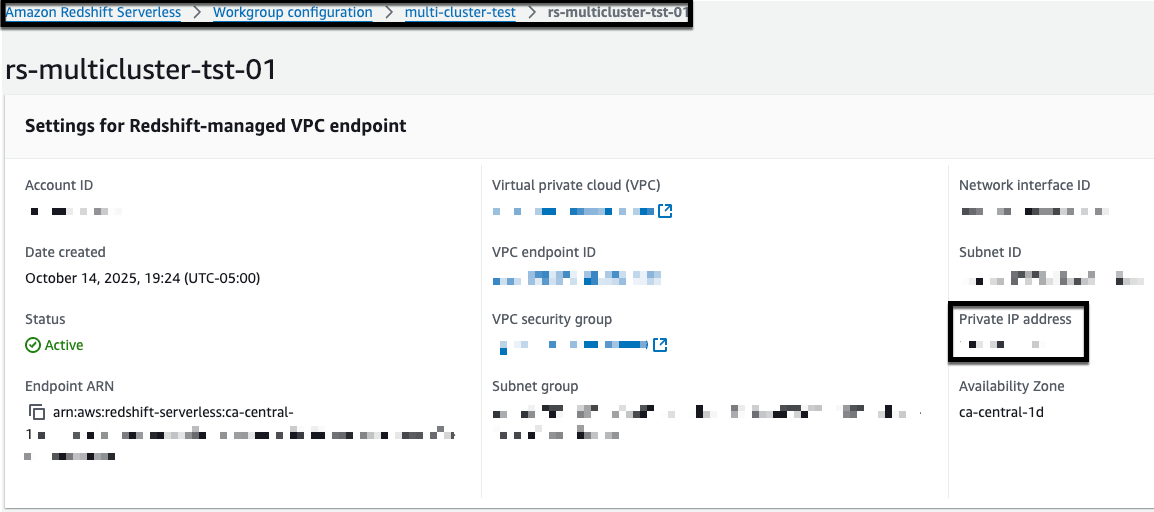
    3. Note the private IP address of your Redshift-managed VPC endpoint.
    4. Repeat for each Amazon Redshift Serverless endpoint that you want to add to the Network Load Balancer.

      Figure 2: Amazon Redshift managed VPC endpoint

      Figure 2: Amazon Redshift managed VPC endpoint

    Next, create a target group for your endpoints:

    1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console.
    2. Choose Target Groups.
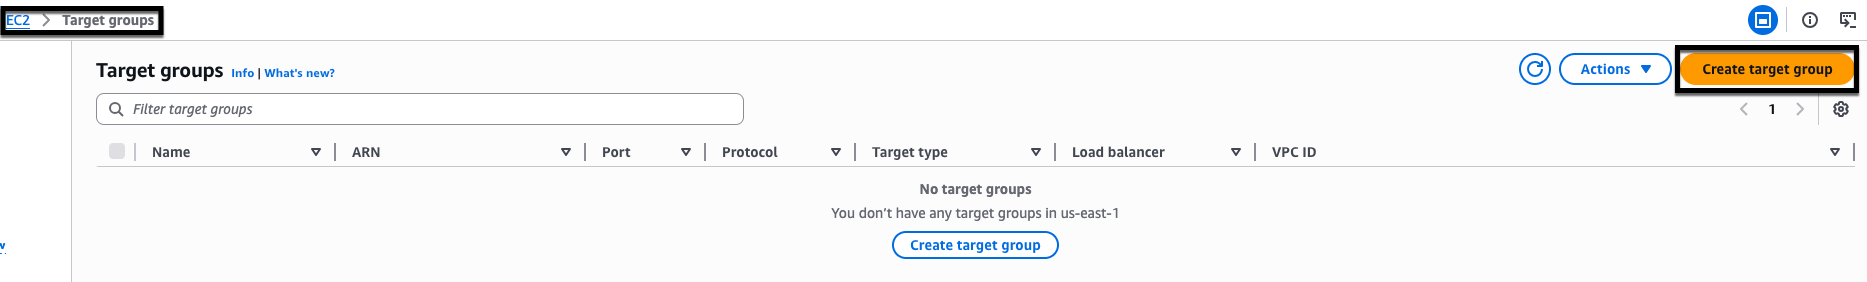
    3. Choose Create target group.
    4. Configure the target group:
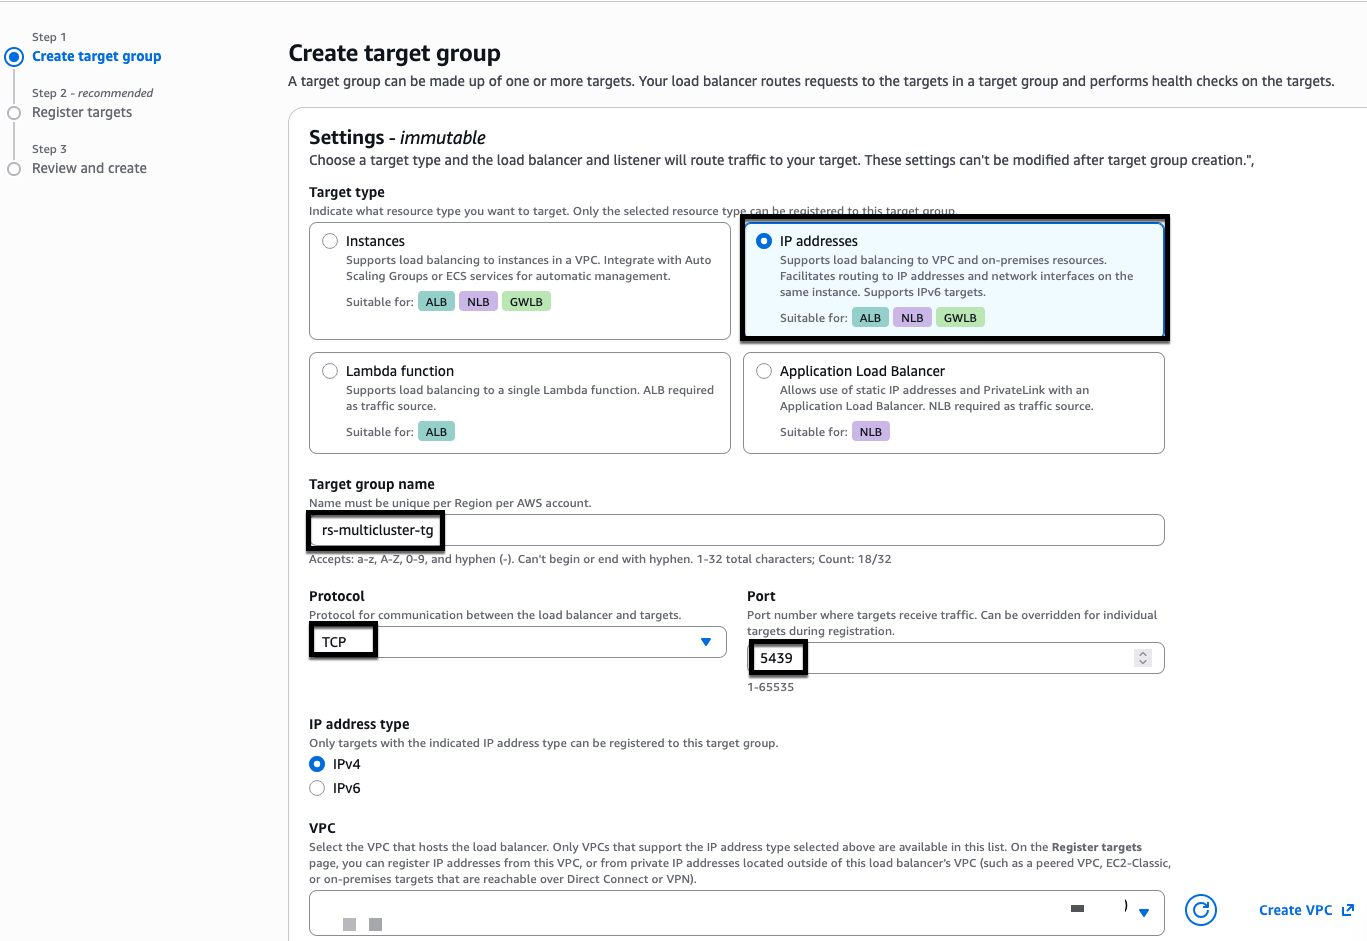
      • For Target type, choose IP addresses.
      • For Target group name, enter rs-multicluster-tg.
      • For Protocol, choose TCP.
      • For Port, enter 5439 (Note: You can find your specific port number in the Redshift endpoint connection details. If you haven’t modified it, use the default port 5439.).
      • For VPC, select your VPC.
      • Choose Next.
      Figure 3: create target group in NLB

      Figure 3: create target group in NLB

      Figure 4: NLB target group creation

      Figure 4: NLB target group creation

    Add a listener to your Network Load Balancer:

    1. In the EC2 console, choose Load Balancers.
    2. Select your Network Load Balancer.
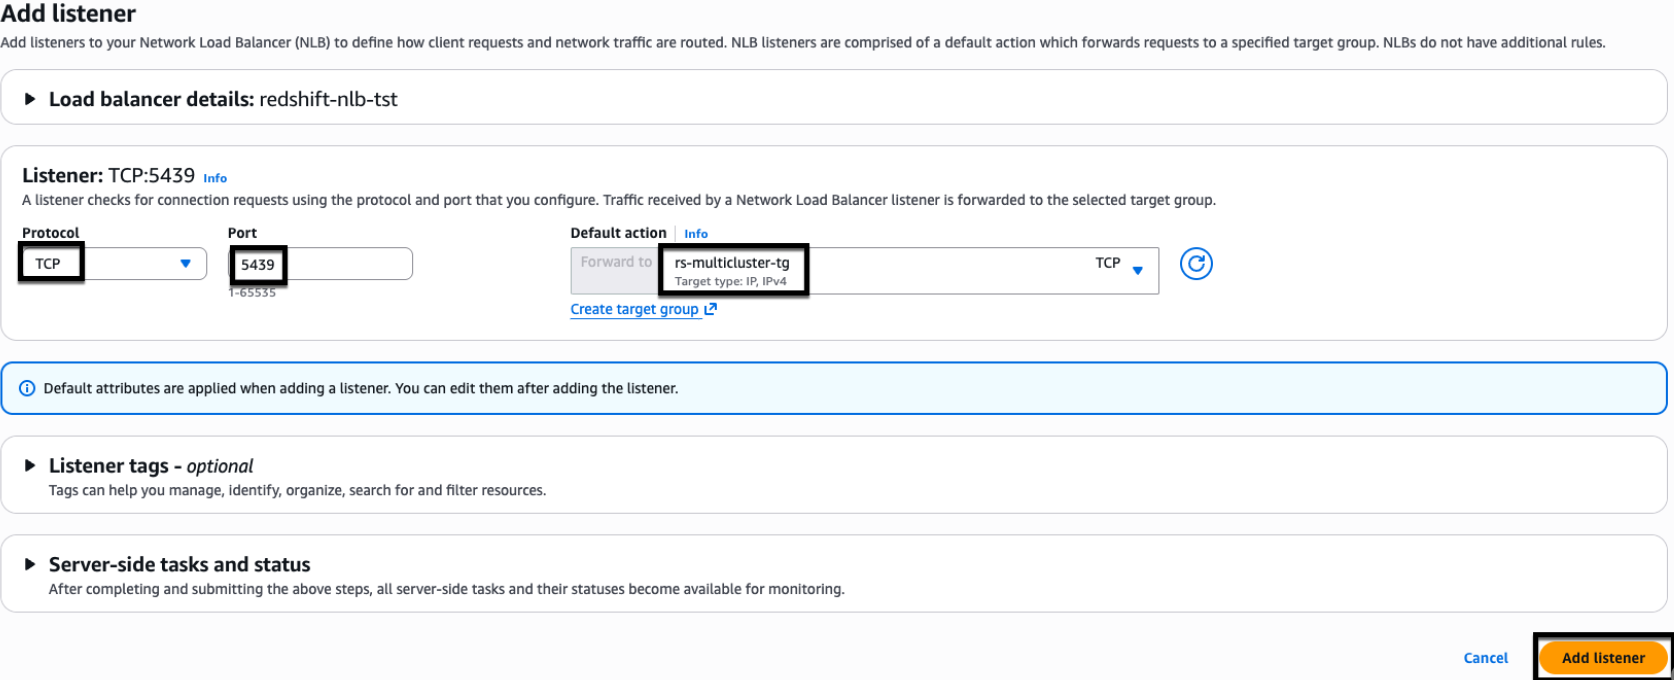
    3. In the Listeners tab, choose Add listener.
    4. Configure the listener:
      • For Protocol, choose TCP.
      • For Port, enter 5439.
      • For Default action, choose rs-multicluster-tg.
    5. Choose Add listener.

      Figure 5: NLB listener properties.

      Figure 5: NLB listener properties.

    2. Configure AWS Certificate Manager (ACM)

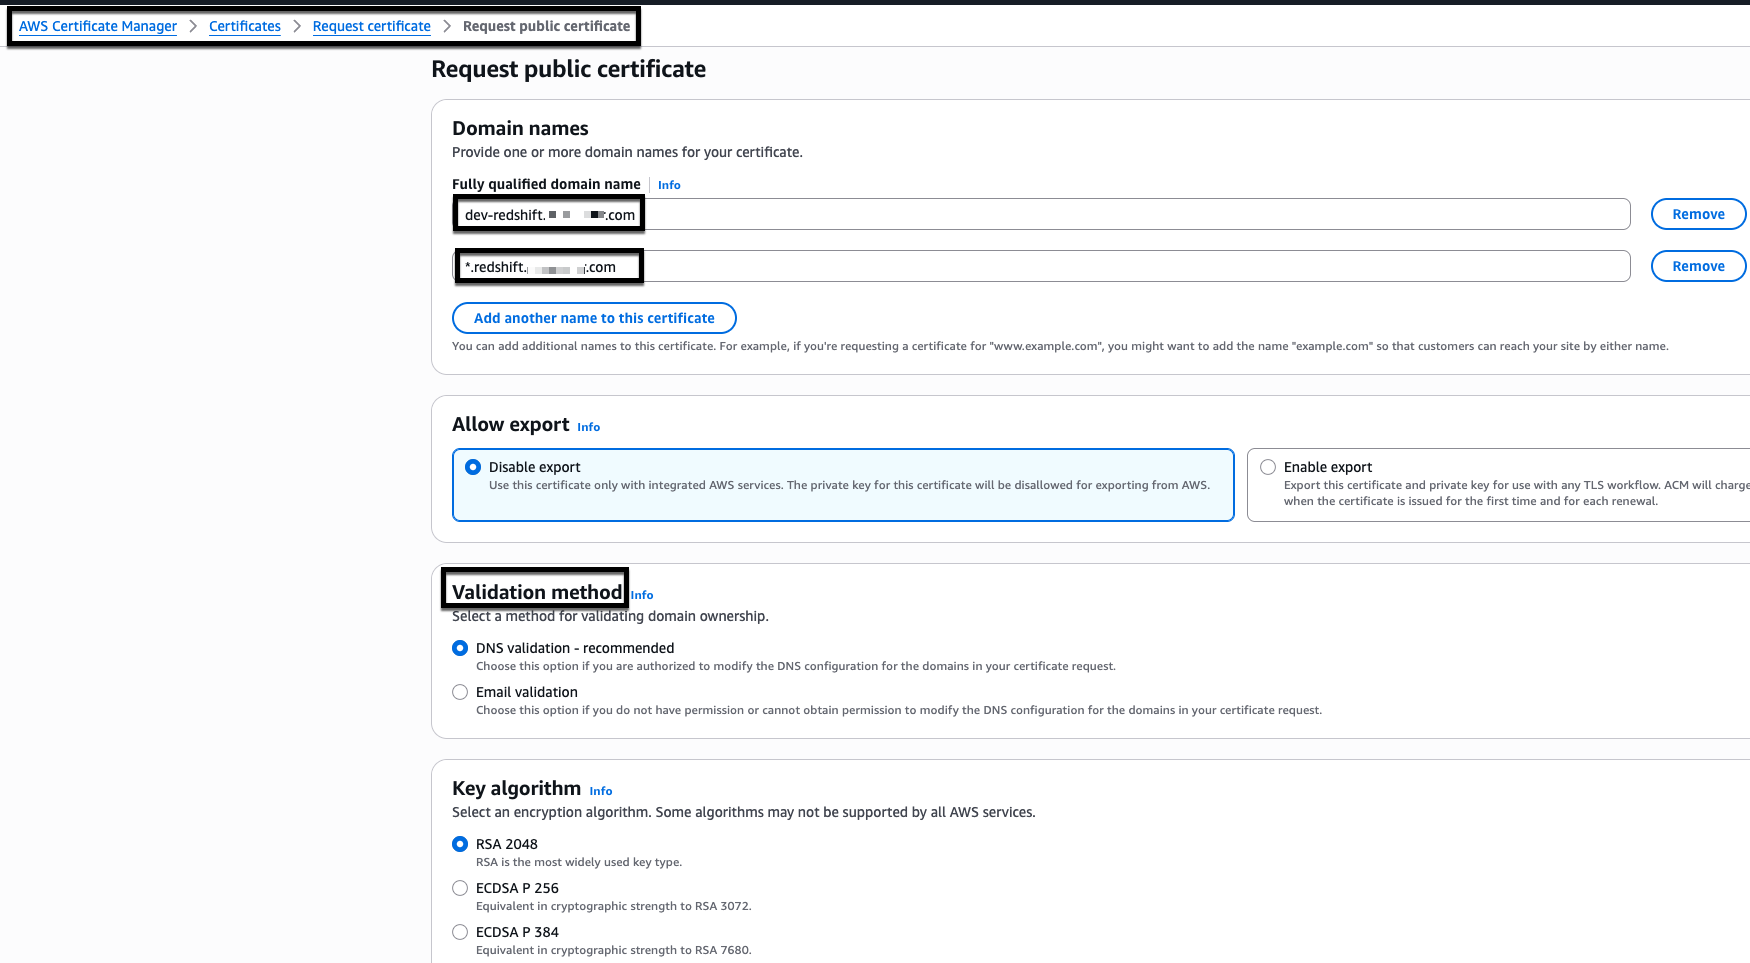
    For this example, we use myexampledomain.com as a custom domain. Replace it with your own domain name before you begin.Follow these steps to request and configure your certificate:

    1. Request a certificate in AWS Certificate Manager (ACM):
      • Open the AWS Certificate Manager console.
      • Choose Request Certificate.
      • Choose Request Public certificate.
      • Choose Next.
    2. Configure the certificate:
      • Add two domain names:
        • Network Load Balancer CNAME: dev-redshift.myexampledomain.com
        • Wildcard domain: *.redshift.myexampledomain.com
      • For Validation method, choose DNS validation.
      • Choose Request.

      For enhanced security, we recommend adding individual Amazon Redshift Serverless CNAMEs instead of using wildcards (*). This example uses DNS validation in AWS Certificate Manager, which requires creating CNAME records to prove domain control.

      Figure 6: AWS Certificate Manager (ACM) certificate creation

      Figure 6: AWS Certificate Manager (ACM) certificate creation

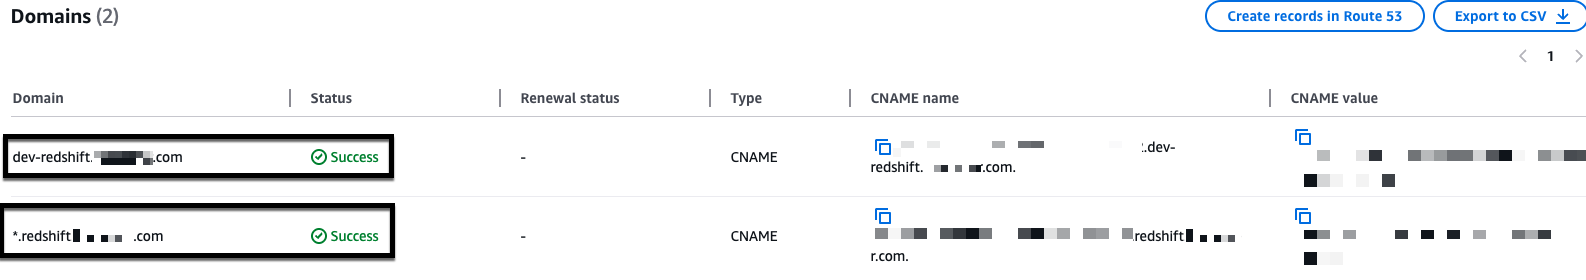
    3. Validate the certificate:
      • Your AWS Certificate Manager (ACM) certificate initially shows a ‘Pending validation’ status.
      • Wait for the status to change to ‘Issued’ before proceeding.
      • You must have an ‘Issued’ status before creating Amazon Redshift custom domain names.
      Figure 7: Sample issued AWS Certificate Manager (ACM) certificate

      Figure 7: Sample issued AWS Certificate Manager (ACM) certificate

    3. Configure Amazon Redshift custom domain names

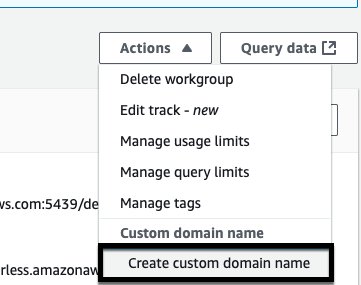
    1. Create a custom domain name:
      • Open the Amazon Redshift Serverless console.
      • Select your workgroup.
      • From Actions, choose Create custom domain name.
      Figure 8: Amazon Redshift custom domain name creation

      Figure 8: Amazon Redshift custom domain name creation

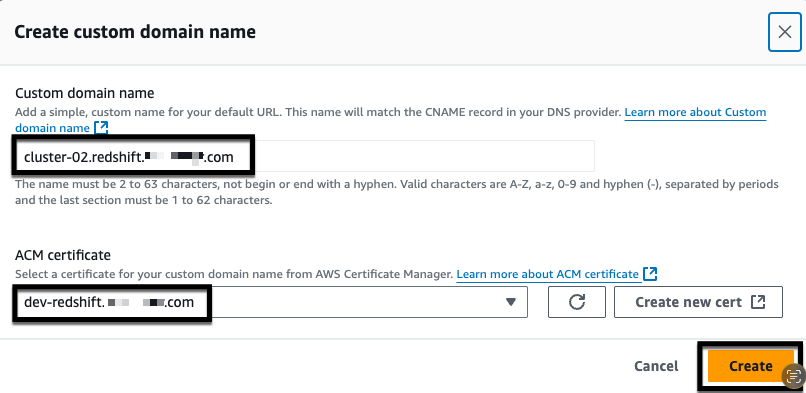
    2. Configure the domain settings:
      • For Custom domain name, enter cluster-02.redshift.myexampledomain.com.
      • For ACM certificate, select the certificate you created for dev-redshift.myexampledomain.com.
      • Choose Create.
      Figure 9: Amazon Redshift custom domain name creation

      Figure 9: Amazon Redshift custom domain name creation

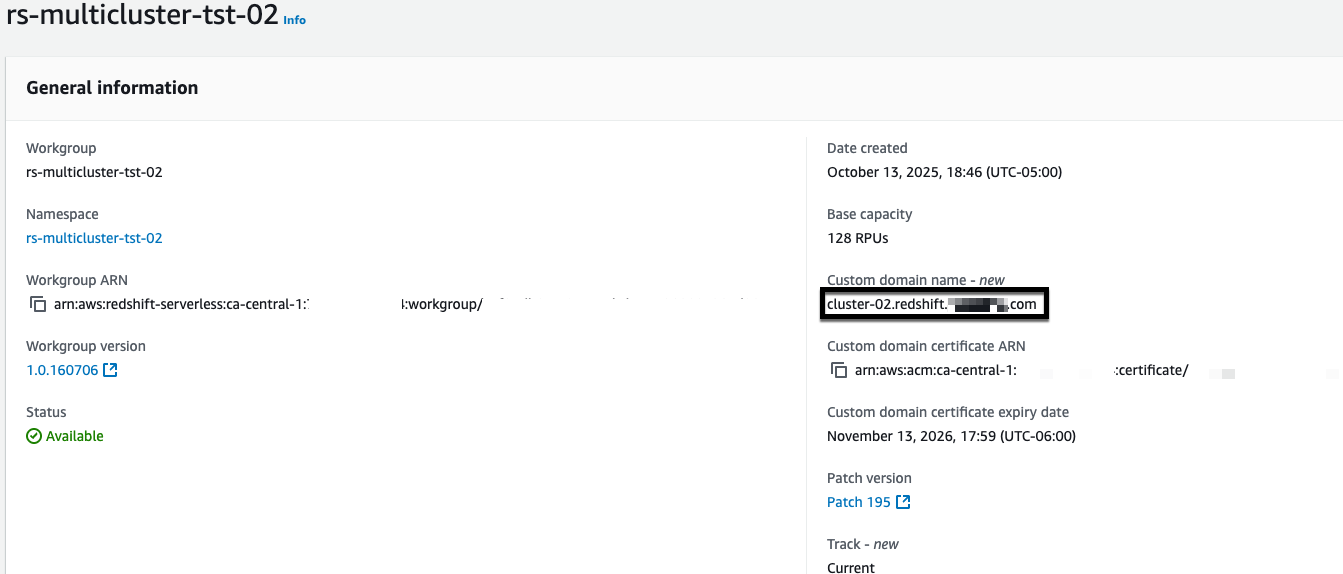
    3. Verify that the custom domain name appears in your workgroup.

      Figure 10: Amazon Redshift custom domain name

      Figure 10: Amazon Redshift custom domain name

    4. Repeat steps 1–3 for each remaining Amazon Redshift Serverless endpoint that you want to add to the Network Load Balancer. Use a unique custom domain name for each endpoint (for example, cluster-03.redshift.myexampledomain.com, cluster-04.redshift.myexampledomain.com) and select the same ACM certificate that you created earlier.

    4. Configure Amazon Route 53

    Amazon Route 53 maps your custom domain name to the correct Amazon Redshift endpoint, making it reachable by name rather than a system-generated address. Without it, clients have no way to resolve your custom domain and AWS Certificate Manager can’t verify domain ownership to enable secure connections.First, create a CNAME record for your Network Load Balancer:

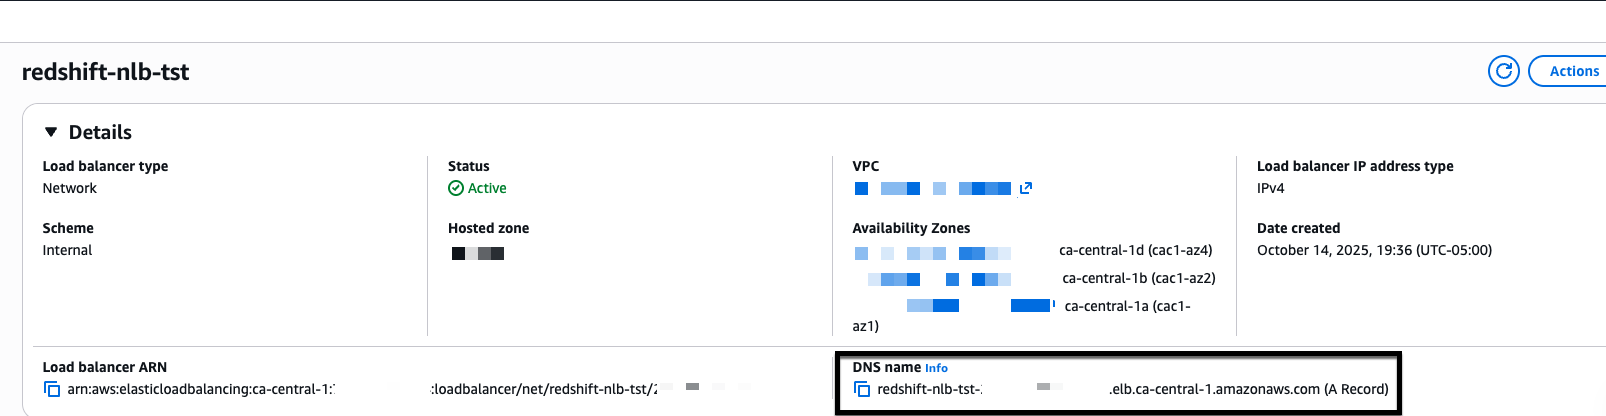
    1. Get the Network Load Balancer DNS name:
      • Open the Amazon EC2 console.
      • Choose Load Balancers.
      • Select your Network Load Balancer.
      • Copy the DNS name.
      Figure 11: NLB DNS name

      Figure 11: NLB DNS name

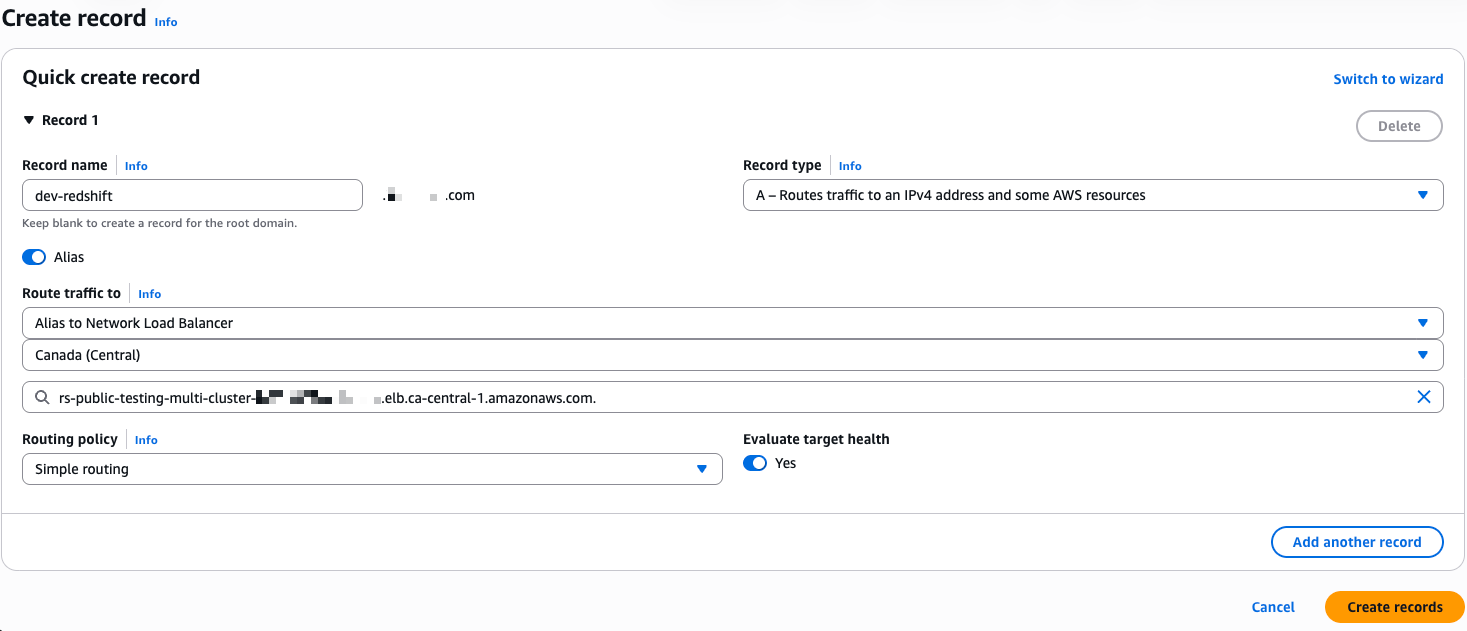
    2. Create Route 53 records:
      • Open the Amazon Route 53 console.
      • Choose Hosted Zones.
      • Select myexampledomain.com.
      • Choose Create record.
      • Configure the record:
        • For Record name, enter dev-redshift.myexampledomain.com.
        • For Record type, choose A – Routes traffic to an IPv4 address and some AWS resources.
        • For Alias, choose Yes.
        • For Route traffic to, choose Alias to Network Load Balancer.
        • Select your AWS Region and Network Load Balancer DNS name.
        • For Routing policy, choose Simple routing.
        • Choose Create records.
      Figure 12: NLB - A record in route 53

      Figure 12: NLB – A record in route 53

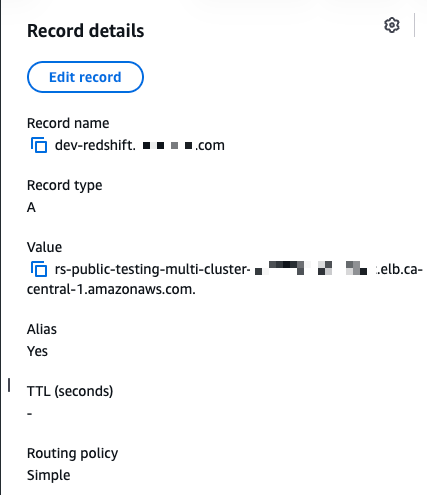
      Figure 13: NLB - A record in Route 53

      Figure 13: NLB – A record in Route 53

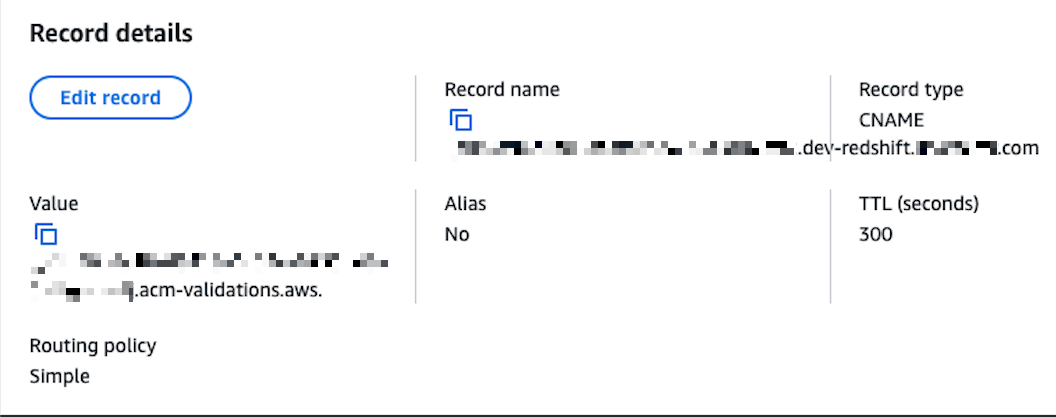
    3. Create the AWS Certificate Manager (ACM) validation CNAME:
      • Open AWS Certificate Manager.
      • Select your certificate for dev-redshift.myexampledomain.com.
      • Copy the CNAME name and CNAME value.
      • Return to Route 53.
      • Create a CNAME record in your myexampledomain.com hosted zone using the values from AWS Certificate Manager (ACM).
      • Choose Create records.
      Figure 14: NLB – CNAME record in Route 53

      Figure 14: NLB – CNAME record in Route 53

    5. Configure Amazon Redshift JDBC and ODBC drivers with native IdP

    The JDBC and ODBC driver configuration connects your client applications to Amazon Redshift through the Network Load Balancer using your Microsoft Entra ID credentials for authentication. Configuring both drivers allows any tool, whether DBeaver using JDBC or Power BI using ODBC, to authenticate through the same identity provider and reach the correct Amazon Redshift endpoint through a single connection point.

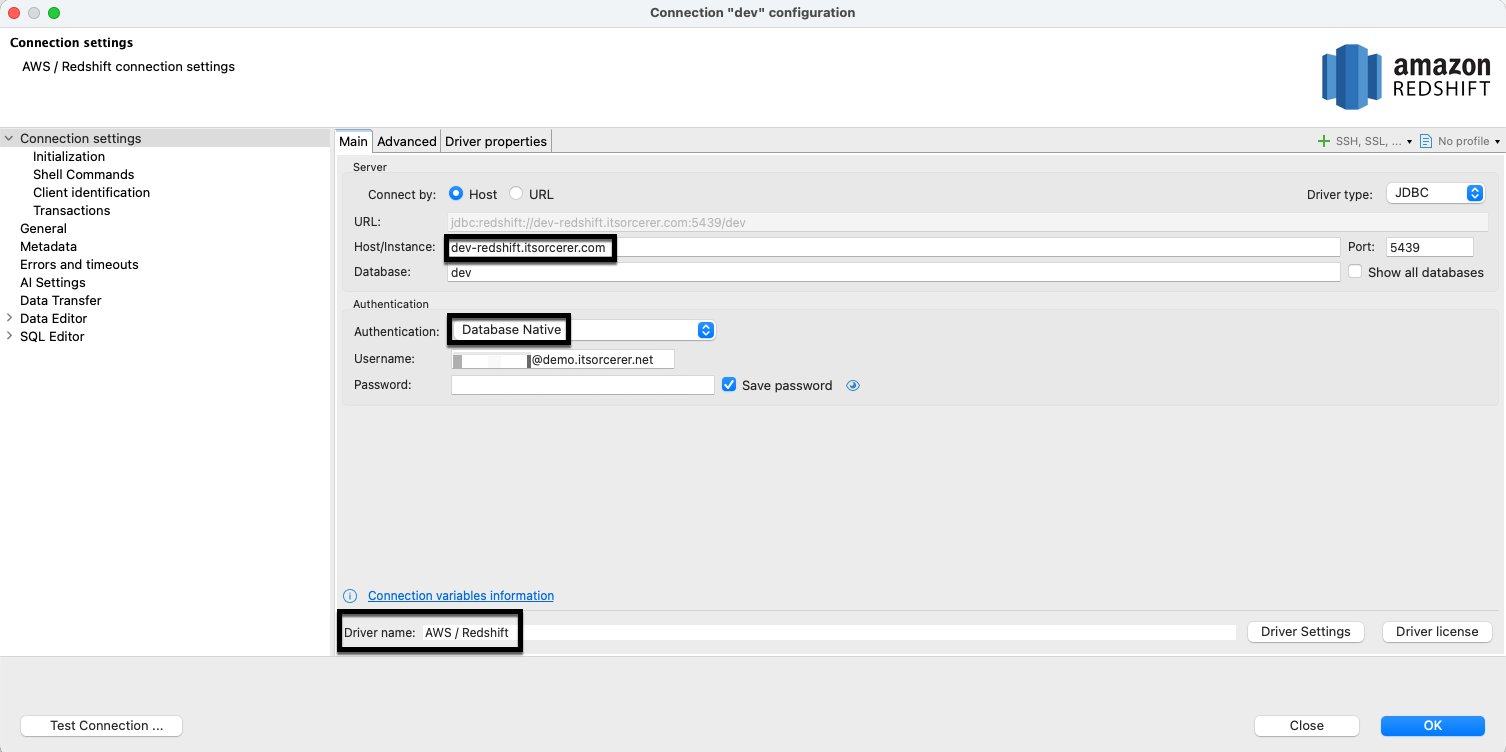
    JDBC driver setup in DBeaver

    1. Create a new Amazon Redshift connection:
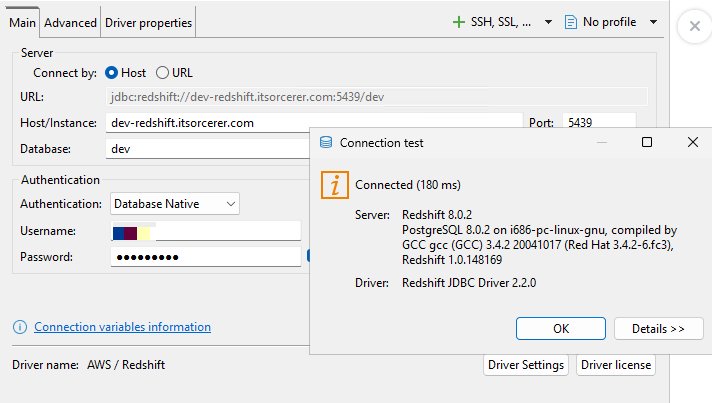
      • Host: dev-redshift.myexampledomain.com (NLB CNAME).
      • Database: dev.
      • Authentication: Database Native.
      • Username: login id for a user account.
      Figure 15: Amazon Redshift JDBC driver setup

      Figure 15: Amazon Redshift JDBC driver setup

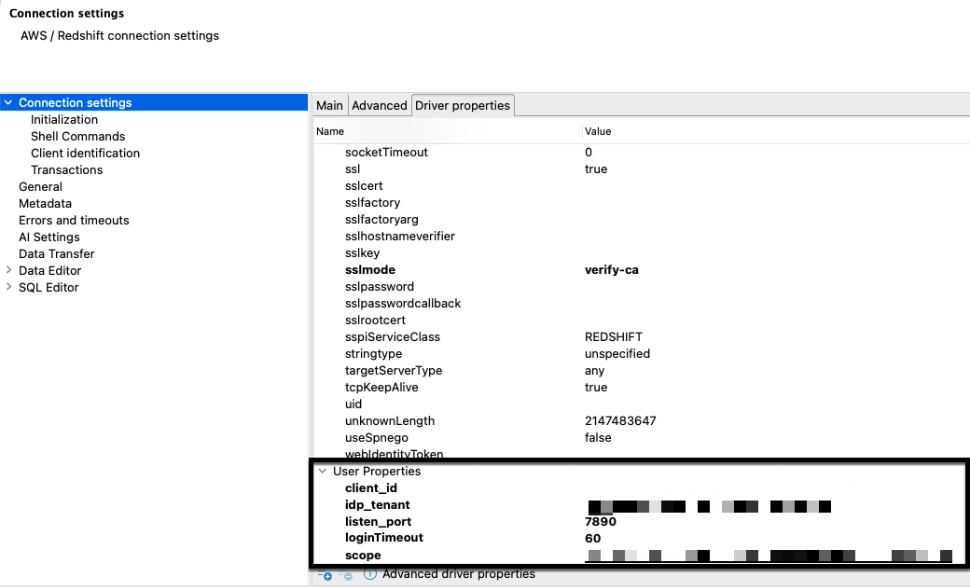
    2. Configure driver properties:
      • plugin_name: com.amazon.redshift.plugin.BrowserAzureOAuth2CredentialsProvider.
      • sslmode: verify-ca.
    3. Add user driver properties:
      • client_id: [Your Microsoft Entra ID application client ID].
      • idp_tenant: [Your Microsoft Entra ID tenant].
      • listen_port: 7890.
      • loginTimeout: 60.
      • scope: [Your Microsoft Entra ID application scope].
      Figure 16: Amazon Redshift JDBC driver user properties

      Figure 16: Amazon Redshift JDBC driver user properties

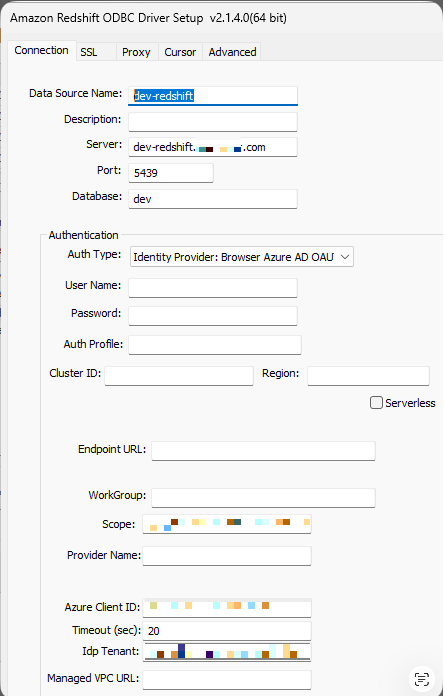
    ODBC driver setup

    1. Configure the system DSN:
      • Open ODBC Data Source Administrator (64-bit).
      • Choose System DSN.
      • Choose Add.
      • Select Amazon Redshift ODBC Driver (x64) 2.01.04.00.
      • Choose Finish.
    2. Configure connection settings:
      • Data Source Name: dev-redshift.
      • Server: dev-redshift.myexampledomain.com.
      • Port: 5439.
      • Database: dev.
      • Auth type: Identity Provider: Browser Azure AD OAUTH2.
      • Scope: [Your Microsoft Entra ID application scope].
      • Azure Client ID: [Your Microsoft Entra ID application client ID].
      • IdP Tenant: [Your Microsoft Entra ID application tenant].
      Figure 17: Amazon Redshift ODBC driver properties

      Figure 17: Amazon Redshift ODBC driver properties

    3. Configure SSL settings:
      • SSL Mode: verify-ca.
      • Choose Save.
      Figure 18: Amazon Redshift ODBC driver properties

      Figure 18: Amazon Redshift ODBC driver properties

    6. Validate connectivity

    Test DBeaver connection

    1. After configuring the JDBC driver properties, choose Test Connection.
    2. Authenticate through the Microsoft login in your browser.
    3. Verify that you receive a success message.
    4. Confirm successful connection using Native IdP through the Network Load Balancer.
    Figure 19: Microsoft Entra id authentication

    Figure 19: Microsoft Entra id authentication

    Figure 20: Successful Microsoft Entra id authentication

    Figure 20: Successful Microsoft Entra id authentication

    Figure 21: Successful Amazon Redshift authentication

    Figure 21: Successful Amazon Redshift authentication

    Test power BI desktop connection

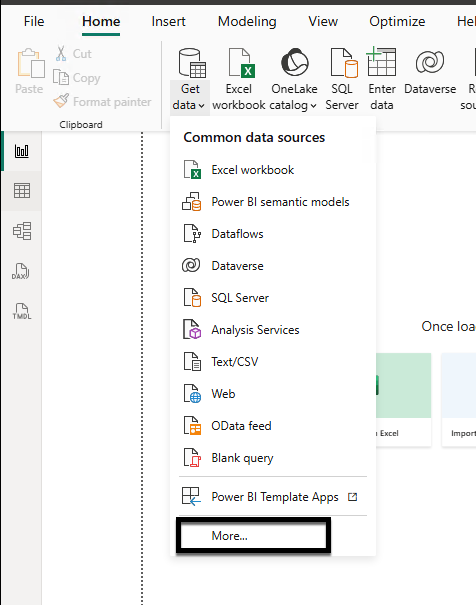
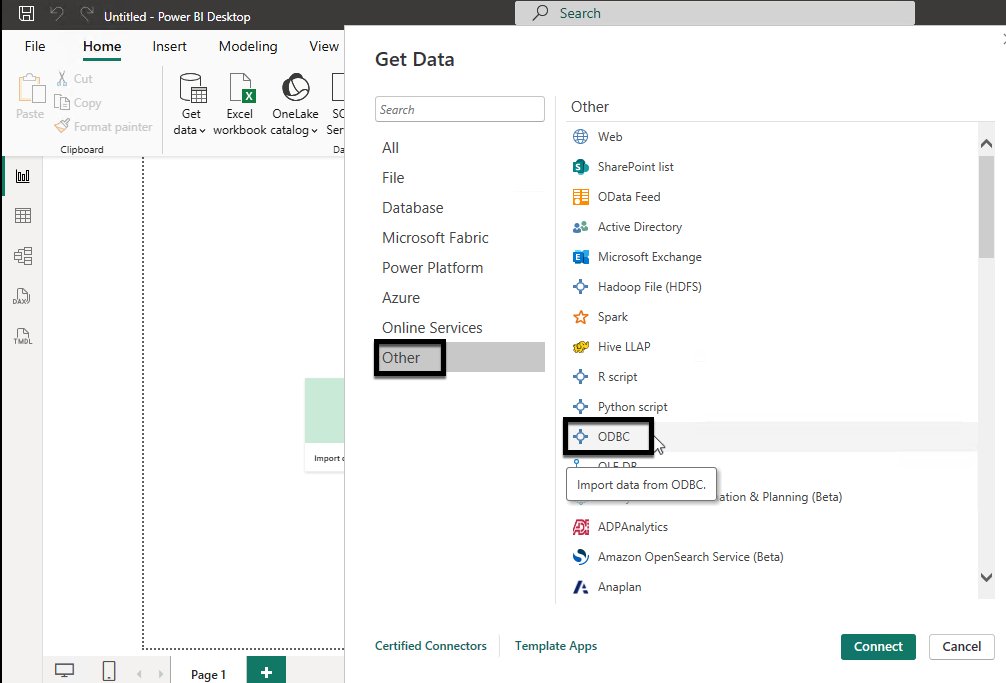
    1. Launch Power BI Desktop:
      • Choose Get data.
      • Choose More.
      • Under Other, select ODBC.
      • Choose Connect.
      Figure 22: Power BI desktop connectivity using Amazon Redshift ODBC driver

      Figure 22: Power BI desktop connectivity using Amazon Redshift ODBC driver

      Figure 23: Power BI desktop connectivity using Amazon Redshift ODBC driver

      Figure 23: Power BI desktop connectivity using Amazon Redshift ODBC driver

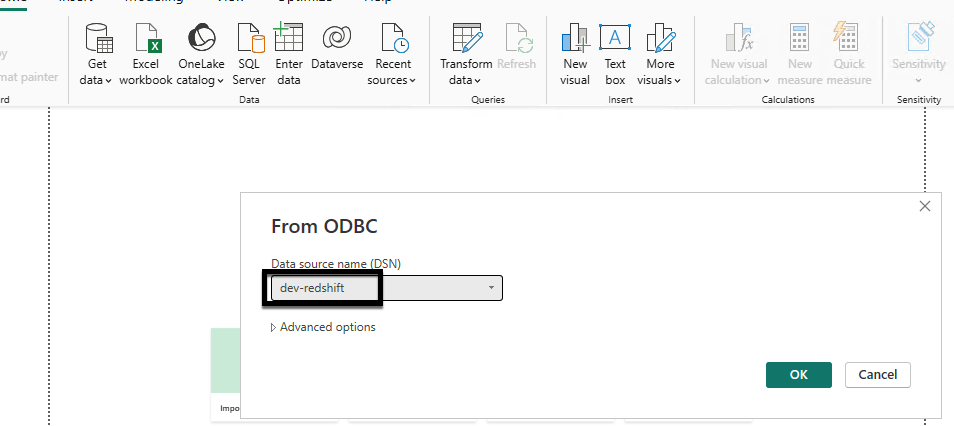
    2. Configure the connection:
      • Select dev-redshift from the Data source name.
      • Choose OK.
      • Complete Microsoft Entra ID authentication in your browser.
      Figure 24: Power bi desktop connectivity using Amazon Redshift odbc driver

      Figure 24: Power bi desktop connectivity using Amazon Redshift odbc driver

      Figure 25: Successful Microsoft Entra id authentication

      Figure 25: Successful Microsoft Entra id authentication

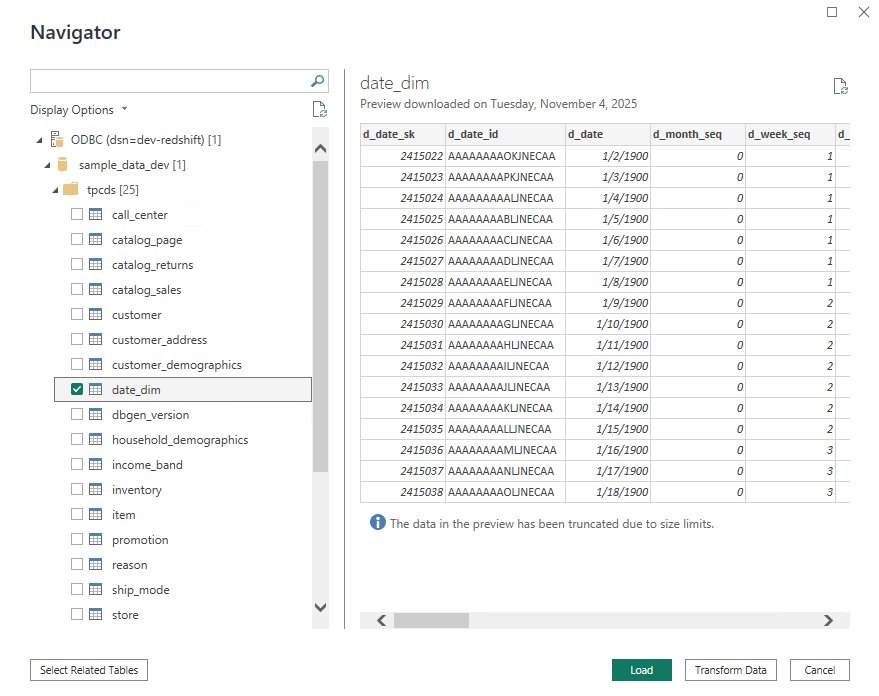
    3. Test the connection:
      • From Navigator, choose schema tpcds.
      • Select date_dim.
      • Choose Load.
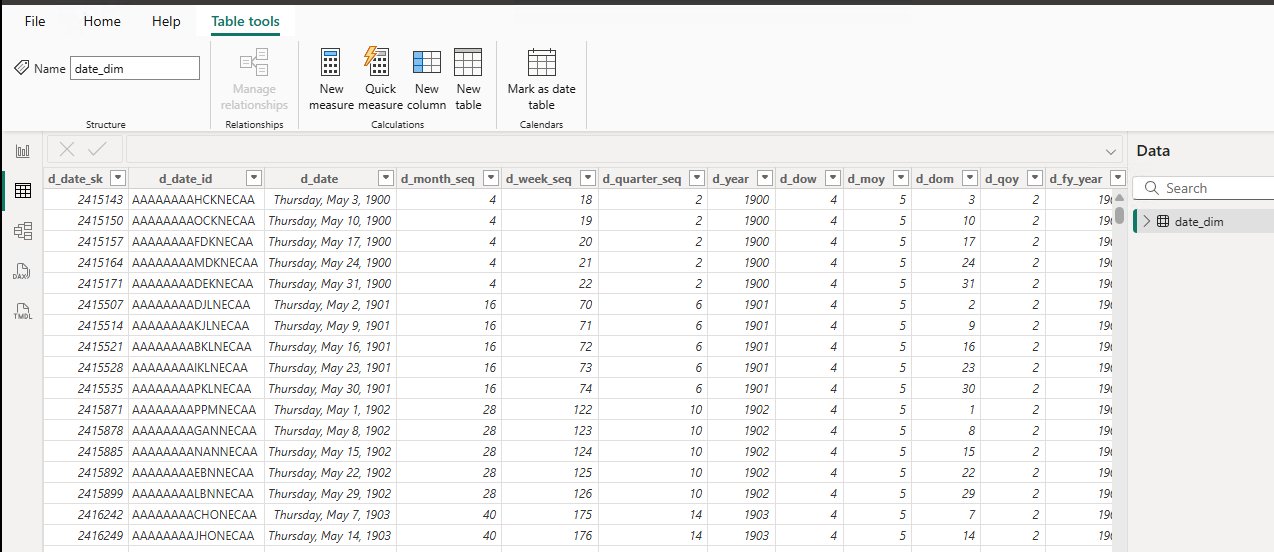
      • Verify that you can analyze your Amazon Redshift data in Power BI Desktop.
      Figure26: Power BI desktop connected to Amazon Redshift and schema browsing

      Figure26: Power BI desktop connected to Amazon Redshift and schema browsing

      Figure 27: Power BI desktop fetching data from date_dim table

      Figure 27: Power BI desktop fetching data from date_dim table

    Cleaning up

    To avoid ongoing charges, delete the following resources:

    1. Delete the Amazon Redshift data warehouses (provisioned cluster or serverless workgroup and namespace) and the VPC endpoints that you created.
    2. Delete the certificate that you created in AWS Certificate Manager (ACM).
    3. Delete the Network Load Balancer.

    Conclusion

    In this post, we showed you how to integrate Amazon Redshift Serverless with Microsoft Entra ID using an AWS Network Load Balancer as a single connection endpoint across multiple workgroups. As your data analytics use cases grow, you can continue to scale horizontally by adding new workgroups behind the same Network Load Balancer without changing your users’ connection settings or authentication experience.

    For more information about extending and scaling this solution, see the following resources:

    AWS Blogs


    About the authors

    Raghu Kuppala

    Raghu Kuppala

    Raghu is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.

    Raza Hafeez

    Raza Hafeez

    Raza is a Senior Product Manager at Amazon Redshift. He has over 13 years of professional experience building and optimizing enterprise data warehouses and is passionate about enabling customers to realize the power of their data. He specializes in migrating enterprise data warehouses to AWS Modern Data Architecture.

    Harshida Patel

    Harshida Patel

    Harshida is a Analytics Specialist Principal Solutions Architect, with AWS.

    Justin Chin-You

    Justin Chin-You

    Justin is a Solutions Architect at AWS, working with Financial Services organizations. He is helping these organizations identify the right cloud transformation strategy based on industry trends and their organizational priorities.

    Implementing HTTP Strict Transport Security (HSTS) across AWS services

    Post Syndicated from Abhishek Avinash Agawane original https://aws.amazon.com/blogs/security/implementing-http-strict-transport-security-hsts-across-aws-services/

    Modern web applications built on Amazon Web Services (AWS) often span multiple services to deliver scalable, performant solutions. However, customers encounter challenges when implementing a cohesive HTTP Strict Transport Security (HSTS) strategy across these distributed architectures.

    Customers face fragmented security implementation challenges because different AWS services require distinct approaches to HSTS configuration, leading to inconsistent security postures.Applications using Amazon API Gateway for APIs, Amazon CloudFront for content delivery, and Application load balancers for web traffic lack unified HSTS policies, leading to complex multi-service environments. Security scanners flag missing HSTS headers, but remediation guidance is scattered across service-specific documentation, causing security compliance gaps.

    HSTS is a web security policy mechanism that protects websites against protocol downgrade attacks and cookie hijacking. When properly implemented, HSTS instructs browsers to interact with applications exclusively through HTTPS connections, providing critical protection against man-in-the-middle issues.

    This post provides a comprehensive approach to implementing HSTS across key AWS services that form the foundation of modern cloud applications:

    1. Amazon API Gateway: Secure REST and HTTP APIs with centralized header management
    2. Application Load Balancer: Infrastructure-level HSTS enforcement for web applications
    3. Amazon CloudFront: Edge-based security header delivery for global content

    By following the implementation steps in this post, you can establish a unified HSTS strategy that aligns with AWS Well-Architected Framework security principles while maintaining optimal application performance.

    Understanding HSTS security and its benefits

    HTTP Strict Transport Security is a web security policy mechanism that helps protect websites against protocol downgrade attacks and cookie hijacking. When a web server declares HSTS policy through the Strict-Transport-Security header, compliant browsers automatically convert HTTP requests to HTTPS for the specified domain. This enforcement occurs at the browser level, providing protection even before the initial request reaches your infrastructure.

    HSTS enforcement applies specifically to web browser clients. Most programmatic clients (such as SDKs, command line tools, or application-to-application communication) don’t enforce HSTS policies. For comprehensive security, configure your applications and infrastructure to only use HTTPS connections regardless of client type rather than relying solely on HSTS for protocol enforcement.

    HTTP to HTTPS redirection enforcement on the server ensures future requests reach your applications over encrypted connections. However, it leaves a security gap during the initial browser request. Understanding this gap helps explain why client-side HSTS serves as an essential security layer in modern web applications.

    For example, when users access web applications, the typical flow with redirects configured is as follows:

    1. User enters example.com in their browser.
    2. Browser sends an HTTP request to http://example.com.
    3. Server responds with HTTP 301/302 redirect to https://example.com.
    4. Browser follows redirection and establishes HTTPS connection

    The initial HTTP request in step 2 creates an opportunity for protocol downgrade issues. An unauthorized party positioned between the user and your infrastructure can intercept this request and respond with content that appears legitimate while maintaining an insecure connection. This technique, known as SSL stripping, can occur even when your server-side AWS infrastructure is properly configured with HTTPS redirects.

    HSTS addresses this security gap by moving security enforcement to the browser level. After a browser receives an HSTS policy, it automatically converts HTTP requests to HTTPS before sending them over the network:

    1. User enters example.com in browser.
    2. Browser automatically converts to HTTPS due to stored HSTS policy.
    3. Browser sends HTTPS request directly to https://example.com.
    4. No initial HTTP request removes the opportunity for interception.

    This browser-level enforcement provides protection that complements your AWS infrastructure security configurations, creating defense in depth against protocol downgrade issues.

    Although current browsers warn about insecure connections, HSTS provides programmatic enforcement. This prevents unauthorized parties from exploiting the security gap because they can’t forge valid HTTPS certificates for protected domains.

    The security benefits of HSTS extend beyond simple protocol enforcement. HSTS helps prevent protocol downgrade issues after HSTS policy is established in the browser. It mitigates against man-in-the-middle issues, preventing unauthorized parties from intercepting communications. It also helps prevent unauthorized session access to protect against credential theft and unintended session access.
    HSTS requires HTTPS connections and removes the option to bypass certificate warnings.

    This post focuses exclusively on implementing the HTTP Strict-Transport-Security header. Although the examples include additional security headers for completeness, detailed configuration of those headers is beyond the scope of this post.

    Key use cases for HSTS implementation

    HSTS protects scenarios that HTTP redirects miss. For example, when legacy systems serve mixed content, or when SSO flows redirect users between providers, HSTS keeps connections encrypted throughout.

    Applications serving both modern HTTPS content and legacy HTTP resources face protocol downgrade risks. When users access example.com/app that loads resources from legacy.example.com, HSTS prevents browsers from making initial HTTP requests to any subdomain, eliminating the vulnerability window during resource loading.

    SSO implementations redirecting users between identity providers and applications create multiple HTTP request opportunities. Due to HSTS, authentication tokens and session data remain encrypted throughout the entire SSO flow, preventing credential interception during provider redirects.

    Microservices architectures using API Gateway often involve service-to-service communication and client redirects. HSTS protects API endpoints from protocol downgrade during initial client connections, which means that API keys and authentication headers are not transmitted over HTTP.

    Applications using CloudFront with multiple origin servers face security challenges when origins change or fail over. HSTS prevents browsers from falling back to HTTP when accessing cached content or during origin failover scenarios, maintaining encryption even during infrastructure changes.

    From an AWS Well-Architected perspective, implementing HSTS demonstrates adherence to the defense in depth principle by adding an additional layer of security at the application protocol level. This approach complements other AWS security services and features, creating a comprehensive security posture that helps to protect data both in transit and at rest.

    Implementing HSTS with Amazon API Gateway

    Amazon API Gateway lacks built-in features to enable HSTS for the API resources. There are several different ways to configure HSTS headers in HTTP APIs and REST APIs.
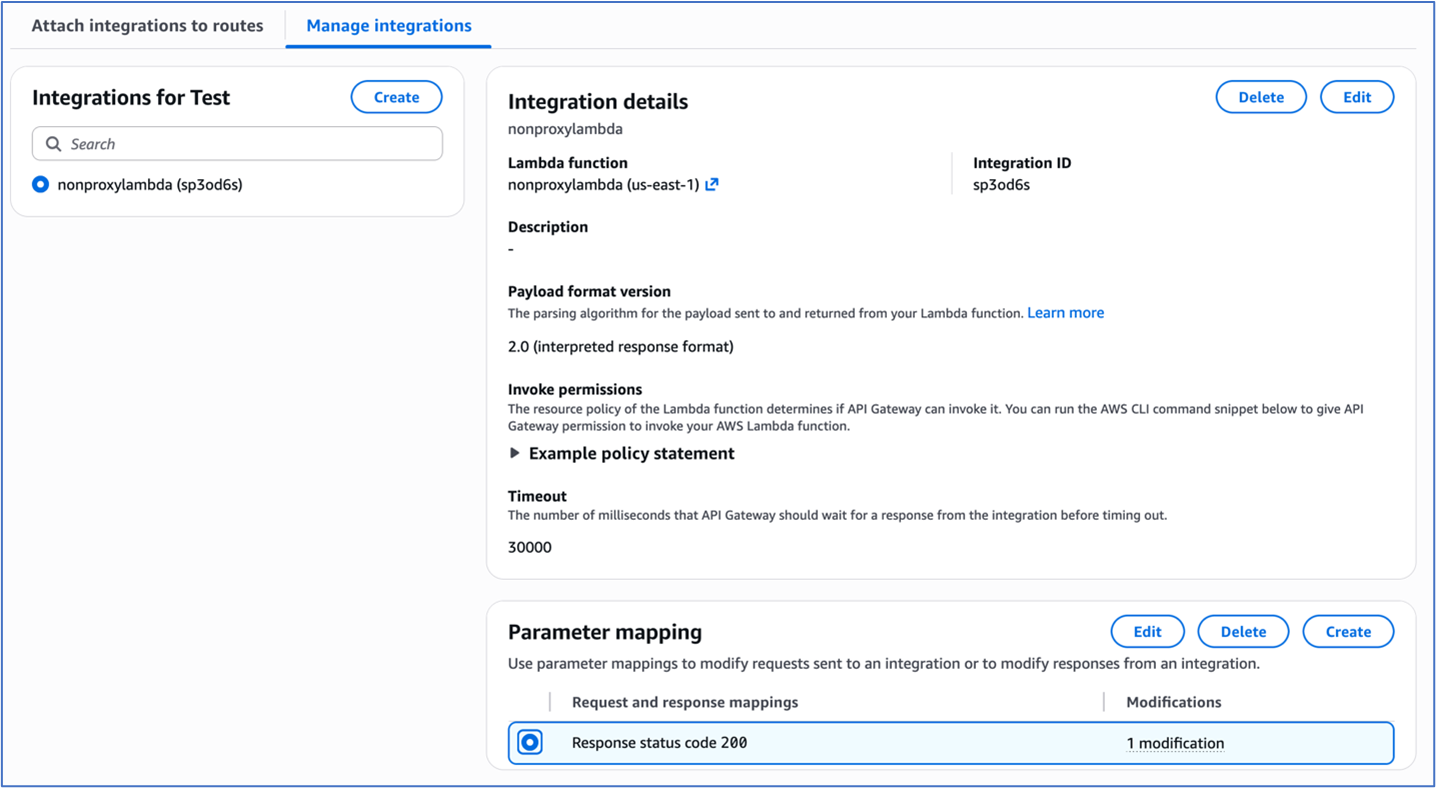
    For HTTP APIs, you can configure response parameter mapping to set HSTS headers when it’s invoked using a default endpoint or custom domain.

    To configure response parameter mapping:

    1. Navigate to your desired HTTP API’s route configuration in the AWS API Gateway console
    2. Access the route’s integration settings under Manage integrations tab.
    Figure 1: Integration settings of the HTTP Api

    Figure 1: Integration settings of the HTTP Api

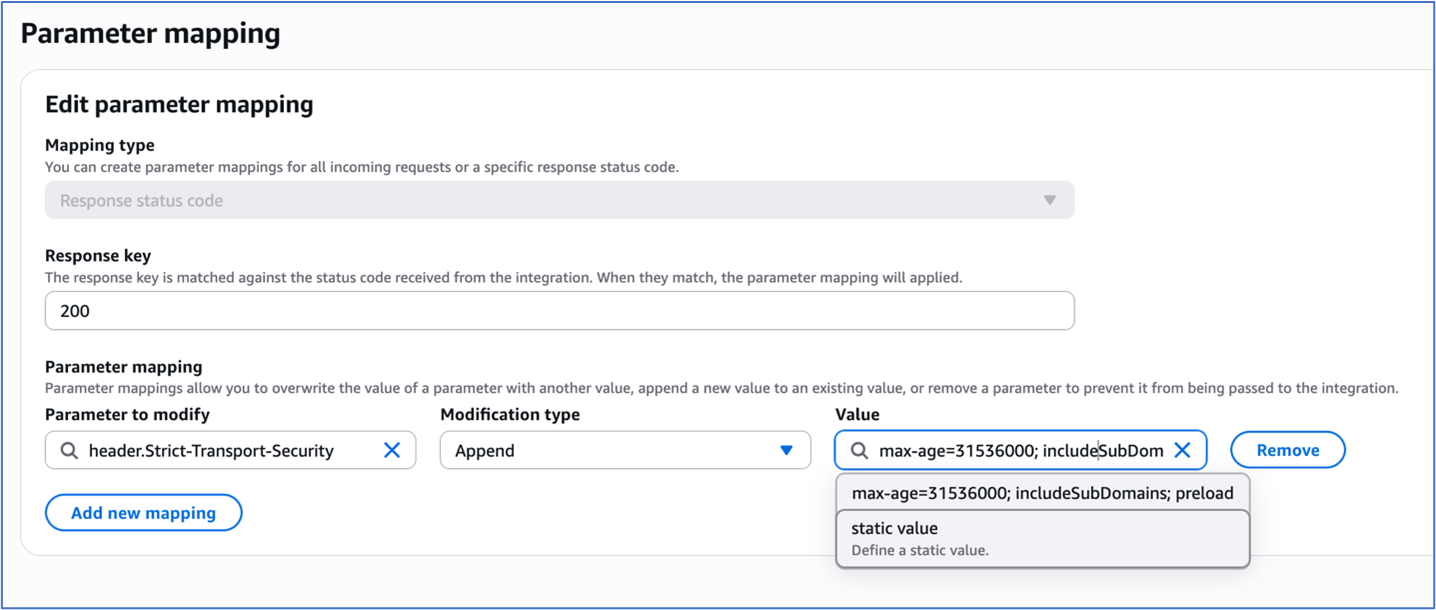
    1. To configure parameter mapping, under Response key, enter 200.
    2. Under Modification type, select Append in the dropdown menu.
    3. Under “Parameter to modify”, enter header.Strict-Transport-Security
    4. Under Value, enter max-age=31536000; includeSubDomains; preload.
    Figure 2: Parameter Mapping for the HTTP Api integration

    Figure 2: Parameter Mapping for the HTTP Api integration

    REST APIs in Amazon API Gateway offer more granular control over HSTS implementation through both proxy and non-proxy integration patterns.

    For proxy integrations, the backend service assumes responsibility for HSTS header generation. For example, an AWS Lambda proxy integration must return the HSTS headers in its response as shown in the following code example:

    import json 
    def lambda_handler(event, context):     
    	return {         
            'statusCode': 200,         
            'headers': {             
                'Strict-Transport-Security': 'max-age=31536000; includeSubDomains; preload'         
            },         
            'body': json.dumps('Secure response with HSTS headers')     
        }

    For non-proxy integrations, the HSTS headers must be returned by the Rest API by implementing one of two methods, either mapping templates or method response.

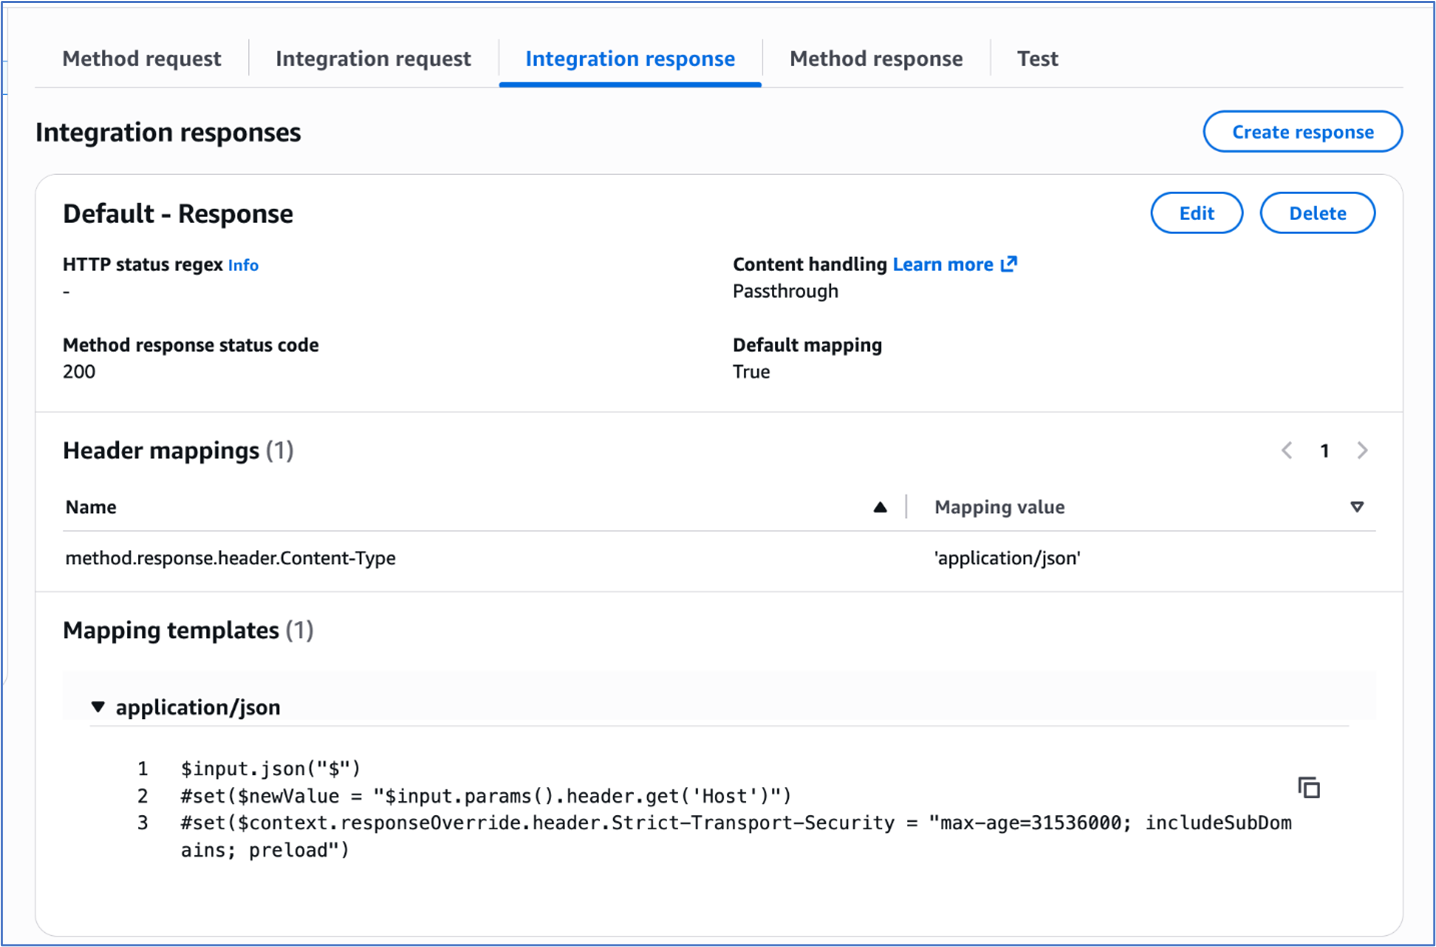
    In the mapping templates method, the mapping template is used to configure the HSTS headers. The Velocity Template Language (VTL) for the mapping template is used for dynamic header generation. To implement this method:

    1. Navigate to the desired REST API and click on the method for the desired resource.
    2. Under the ‘Integration response’ tab, use the following mapping template to set the response headers:
    $input.json("$") 
    #set($newValue = "$input.params().header.get('Host')") 
    #set($context.responseOverride.header.Strict-Transport-Security 
    = "max-age=31536000; includeSubDomains; preload")

    Figure 3: Adding mapping template to integration response of the Rest Api

    Figure 3: Adding mapping template to integration response of the Rest Api

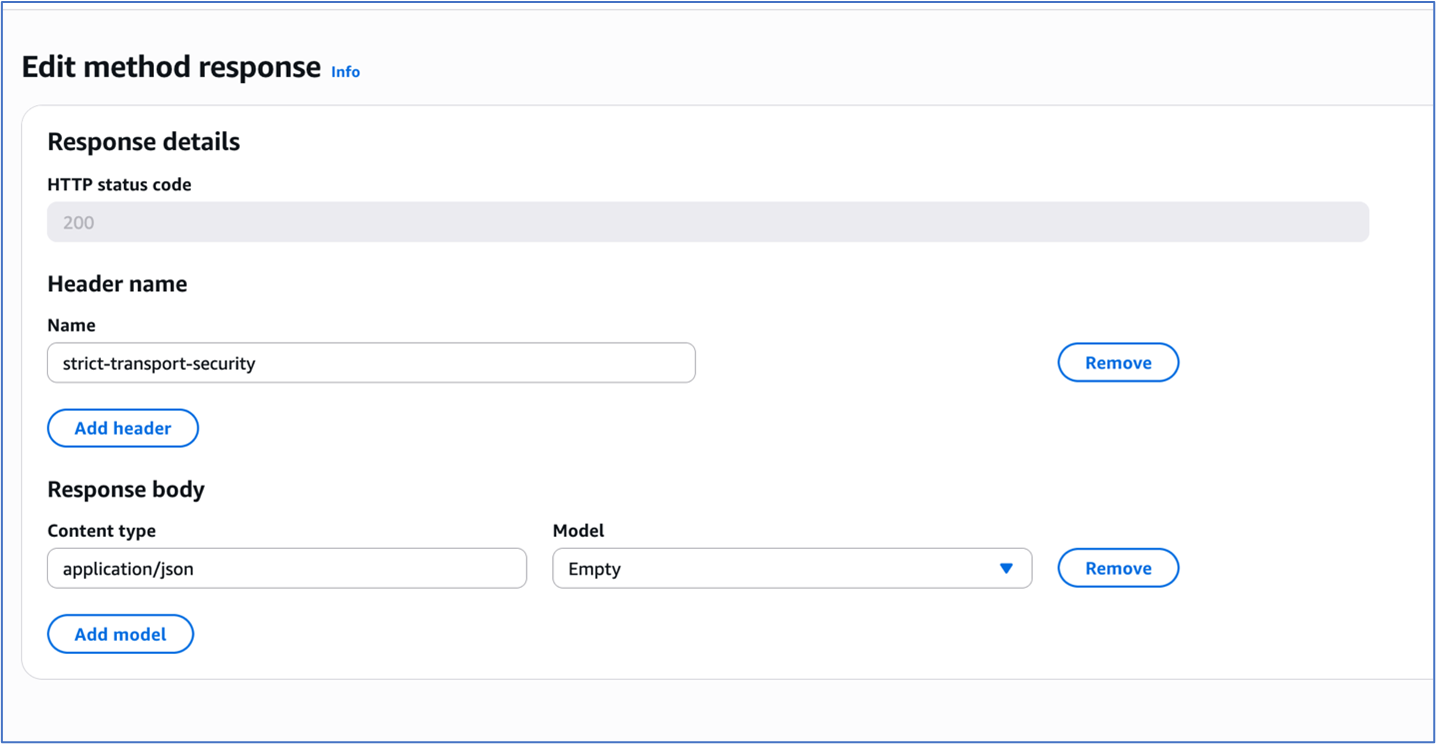
    The ‘Method response’ tab provides declarative configuration through explicit header mapping in the configuration. To implement this method:

    1. Navigate to your desired REST API and select the method for the desired resource.
    2. Choose Method response and under Header name, add the HSTS header strict-transport-security.
    Figure 4: Method response of the Rest Api

    Figure 4: Method response of the Rest Api

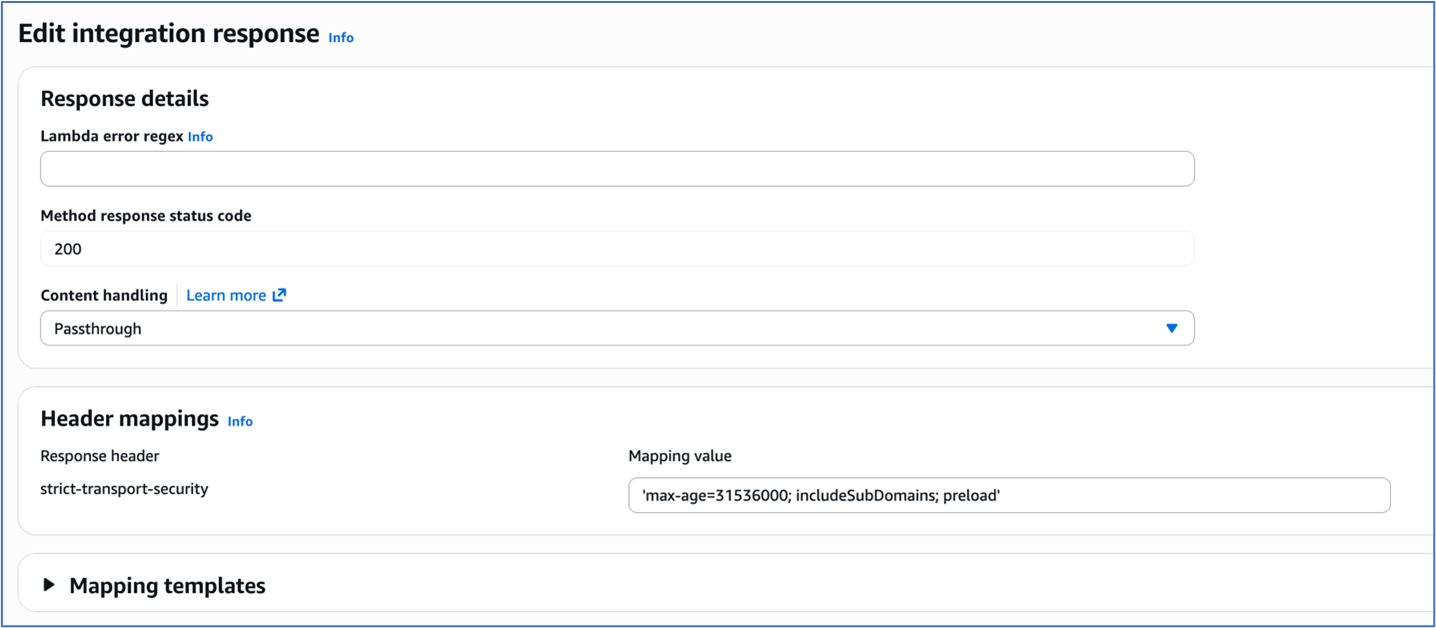
    3. Choose Integration response and under Header mappings, enter the HSTS header strict-transport-security. Add the Mapping value for the header as max-age=31536000; includeSubDomains; preload.

    Figure 5: Integration response of the Rest Api

    Figure 5: Integration response of the Rest Api

    To test and validate, use the following command:

    Verify HSTS implementation for both HTTP API and REST API using curl with response headers logged:

    curl -i https://your-api-gateway-url.execute-
    api.region.amazonaws.com/stage/resource

    The expected response should include:

    HTTP/2 200 
    
    date: Tue, 20 Sep 2025 16:34:35 GMT 
    content-type: application/json 
    content-length: 3 
    x-amzn-requestid: 76543210-9aaa-4bbb-accc-987654321012
    strict-transport-security: max-age=31536000; includeSubDomains; preload 
    x-amz-apigw-id: ABCDEFGHIJKLMNO

    Implementing HSTS with AWS Application Load Balancers

    Application Load Balancers now provide built-in support for HTTP response header modification, including HSTS headers. This lets you enforce consistent security policies across all your services from a single point, reducing development effort and ensuring uniform protection regardless of which backend technologies you’re using.

    Prerequisites and infrastructure requirements

    Before implementing HSTS with load balancers, ensure your infrastructure meets these requirements:

    • Functional HTTPS listener – The ALB listener must be configured with HTTPS correctly.
    • Valid certificates – The ALB listener must have proper TLS certificate chain in AWS Certificate Manager and validation.
    • Application Load Balancer – The header modification feature for the ALB must be enabled for the listener since it is turned off by default.

    Configuration

    Application Load Balancers support direct HSTS header injection through the response header modification feature. This approach provides centralized security policy enforcement without requiring individual application configuration.

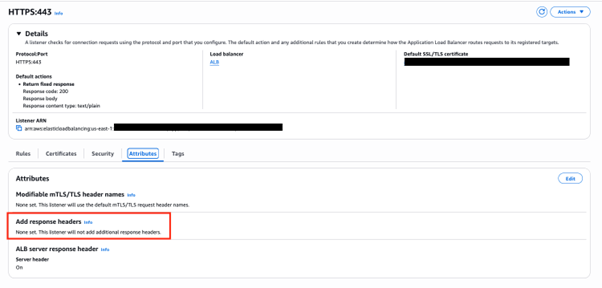
    To enable HTTP header modification for your Application Load Balancer:

    1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console and navigate to Load Balancers.
    2. Select your Application Load Balancer.
    3. On the Listeners and rules tab, select the HTTPS listener.
    4. On the Attributes tab, choose Edit.
      Figure 6: ALB HTTPS listener Attributes configuration

      Figure 6: ALB HTTPS listener Attributes configuration

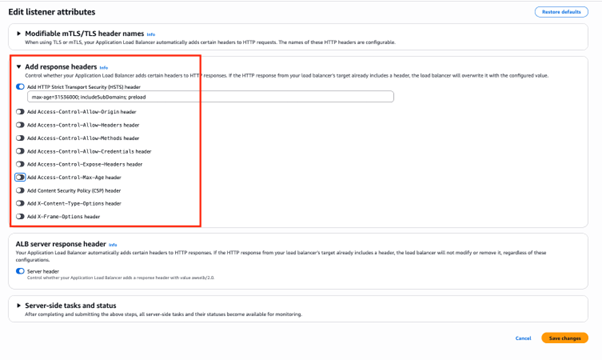
    5. Expand the Add response headers section.
    6. Select Add HTTP Strict Transport Security (HSTS) header.
    7. To configure the header value, enter max-age=31536000; includeSubDomains; preload.
    8. Choose Save changes.
    Figure 7: Add response headers in attributes configuration of the ALB HTTPS listener

    Figure 7: Add response headers in attributes configuration of the ALB HTTPS listener

    Header modification behavior

    When ALB header modification is enabled:

    • Header addition – If the backend response doesn’t include the specified header, ALB adds it with the configured value
    • Header override – If the backend response includes the header, ALB replaces the existing value with the configured value
    • Centralized control – Responses from the load balancer include the configured security headers, ensuring consistent policy enforcement

    To test and validate, use the following command:
    curl -I https://my-loadbalancer-1234567890.us-west-2.elb.amazonaws.com

    The following code example shows the expected response headers:

    HTTP/2 200
    date: Tue, 23 Sep 2025 16:34:35 GMT
    strict-transport-security: max-age=31536000; includeSubDomains; preload

    Header value constraints:

    • Maximum header value size – 1 KB
    • Supported characters – Alphanumeric (a-z, A-Z, 0-9) and special characters (_ :;.,/’?!(){}[]@<>=-+*#&`|~^%)
    • Empty values revert to default behavior (no header modification)

    When implementing header modifications, there are several operational considerations to keep in mind. Header modification must be explicitly enabled on each listener where you want the functionality to work. Once enabled, any changes you configure will apply to all responses that come from the load balancer, affecting every request processed through that listener. Application Load Balancer performs basic input validation on the headers you configure, but it has limited capability for header-specific validation, so you should ensure your header configurations follow proper formatting and standards.

    This built-in Application Load Balancer capability significantly simplifies HSTS implementation by eliminating the need for backend application modifications while providing centralized security policy enforcement across your entire application infrastructure.

    Implementing HSTS with Amazon CloudFront

    Amazon CloudFront provides built-in support for HTTP security headers, including HSTS, through response headers policies. This feature enables centralized security header management at the CDN edge, providing consistent policy enforcement across cached and non-cached content.

    Response headers policy configuration

    You can use the CloudFront response headers policy feature to configure security headers that are automatically added to responses served by your distribution. You can use managed response headers policies that include predefined values for the most common HTTP security headers. Or, you can create a custom response header policy with custom security headers and values that you can add to the required CloudFront behavior.

    To configure security headers:

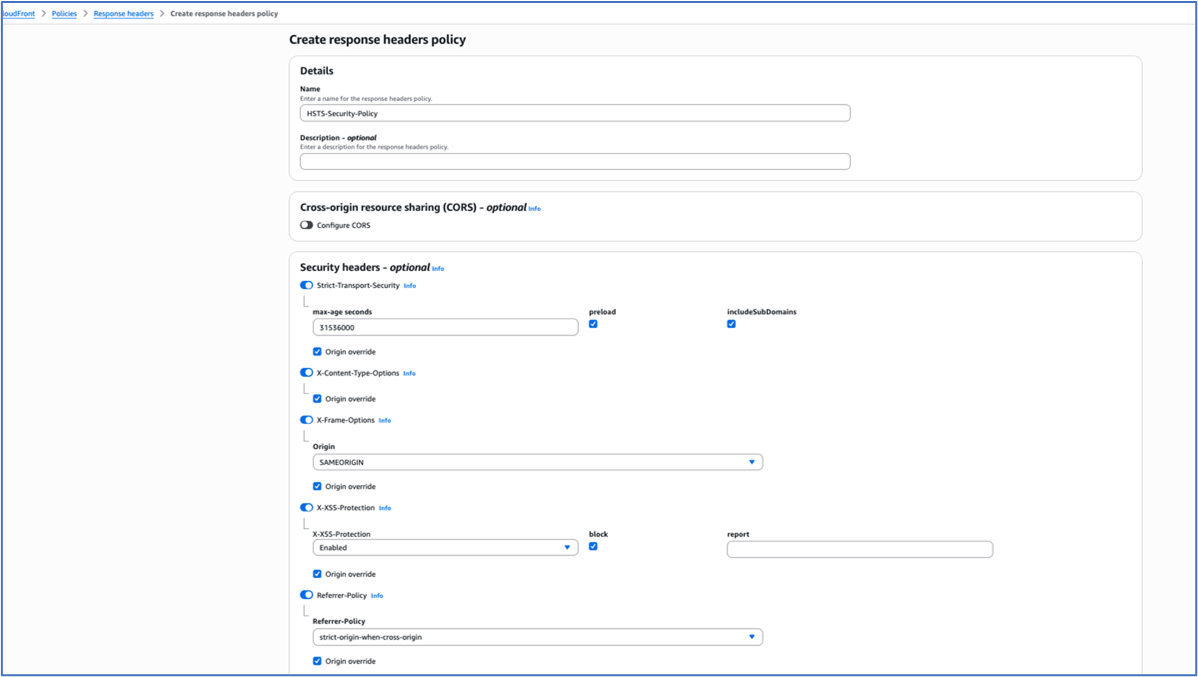
    1. On the CloudFront console, navigate to Policies and then Response headers.
    2. Choose Create response headers policy.
    3. Configure policy settings:
      • NameHSTS-Security-Policy
      • Description – HSTS and security headers for web applications
    4. Under Security headers, configure:
      • Strict Transport Security – Select
      • Max age – 31,536,000 seconds (1 year)
      • Preload – Select (optional)
      • IncludeSubDomains – Select (optional)
    5. Add additional security headers:

      • X-Content-Type-Options
      • X-Frame-Options – Select Origin as “SAMEORIGIN”
      • Referrer-Policy – Select “strict-origin-when-cross-origin”
      • X-XSS-Protection – Select “Enabled”, Tick “Block”
      • Choose Create.
    Figure 8: Configuring response header policy for the Cloudfront distribution

    Figure 8: Configuring response header policy for the Cloudfront distribution

    To attach the policy to the distribution:

    1. Navigate to your CloudFront distribution.
    2. Select the Behaviors tab.
    3. Edit the default behavior (or create a new one).
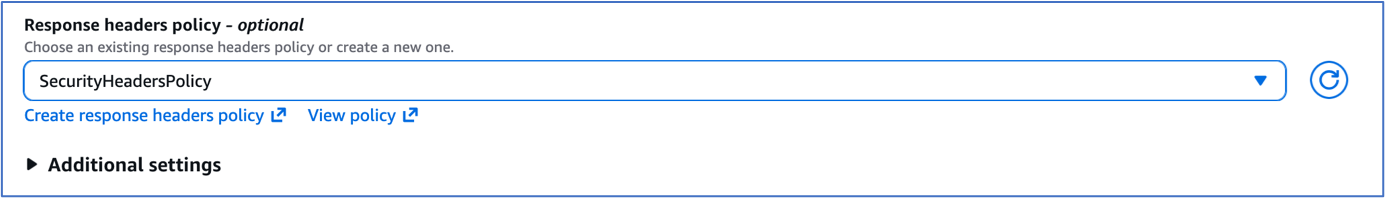
    4. Under Response headers policy, select your created policy.
    5. Choose Save changes.
    Figure 9: Selecting the response headers policy

    Figure 9: Selecting the response headers policy

    Header override behavior:
    CloudFront response headers policies provide origin override functionality that controls how headers are managed between the origin and CloudFront. When origin override is enabled, CloudFront will replace existing headers that come from the origin server. Conversely, when origin override is disabled, CloudFront will only add the policy-defined headers if those same headers are not already present in the origin response, preserving the original headers from the source.

    To test and validate, use the following command:

    curl -I https://your-cloudfront-domain.cloudfront.net

    The following code example shows the expected response headers:

    HTTP/2 200 
    date: Tue, 23 Sep 2025 16:34:35 GMT 
    strict-transport-security: max-age=31536000; includeSubDomains; preload 
    x-content-type-options: nosniff 
    x-frame-options: SAMEORIGIN 
    referrer-policy: strict-origin-when-cross-origin 
    x-xss-protection: 1; mode=block 
    x-cache: Hit from cloudfront

    Using CloudFront has several advantages. It offers consistent header application across all content types and centralized security policy management. Edge-level enforcement reduces latency, and no origin server modifications are required. AWS edge locations offer global policy distribution.

    Security considerations and best practices

    Implementing HSTS requires careful consideration of several security implications and operational requirements.

    The max-age directive determines how long browsers will enforce HTTPS-only access. The duration guidelines are as follows:

    • 300 seconds (5 minutes) – Safe for experimentation during initial testing phase.
    • 86,400 seconds (1 day) – For short-term commitment such as development environments.
    • 259,2000 seconds (30 days) – For medium-term validation such as staging environments.
    • 31,536,000 seconds (1 year) – For long-term commitment such as production environments.

    We recommend that you start with shorter max-age values during initial implementation and gradually increase them as you gain confidence in your HTTPS infrastructure stability.

    The includeSubDomains directive extends HSTS enforcement to all subdomains. It offers several benefits, including comprehensive protection across the entire domain hierarchy, prevention of subdomain-based attacks, and simplified security policy management.

    Requirements for using this directive include:

    • Subdomains should support HTTPS to use this directive effectively.
    • Subdomains should have valid SSL certificates.
    • You must maintain a consistent security policy across domain hierarchy.

    Consider implementing HSTS preloading for maximum security coverage:

    Strict-Transport-Security: max-age=31536000; includeSubDomains; preload

    Preloading benefits include protection for first-time visitors, browser-level enforcement before network requests, and maximizing security coverage.

    The following are some preloading considerations:

    • It requires submission to browser preload lists.
    • It’s difficult to reverse because removal takes months.
    • It requires long-term commitment to HTTPS infrastructure.

    For more information, see:

    Conclusion

    Implementing HSTS across AWS services provides a robust foundation for securing web applications against protocol downgrade attacks and enabling encrypted communications. By using the built-in capabilities of API Gateway, CloudFront, and Application Load Balancers, organizations can create comprehensive security policies that align with AWS Well-Architected Framework principles.

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
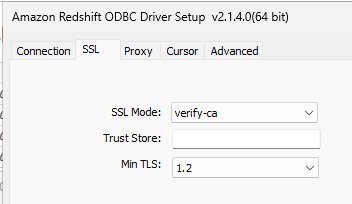
    Abhishek Avinash Agawane
    Abhishek Avinash Agawane

    Abhishek is a Security Consultant at Amazon Web Services with more than 8 years of industry experience. He helps organizations architect resilient, secure, and efficient cloud environments, guiding them through complex challenges and large-scale infrastructure transformations. He has helped numerous organizations enhance their cloud operations through targeted optimizations, robust architectures, and best-practice implementations.

    How CommBank made their CommSec trading platform highly available and operationally resilient

    Post Syndicated from Kris Severijns original https://aws.amazon.com/blogs/architecture/how-commbank-made-their-commsec-trading-platform-highly-available-and-operationally-resilient/

    CommSec, Australia’s leading online broker and a subsidiary of the Commonwealth Bank of Australia (CommBank), helps millions of customers grow their wealth by making it easy, accessible and affordable to invest in both Australian and international markets.

    CommSec plays an essential role in customers’ financial journeys, providing essential services such as market research, portfolio management, and trade execution. With customers expecting round-the-clock availability, the platform must maintain exceptional reliability. Additionally, as a regulated entity under the Australian Securities & Investments Commission (ASIC), CommSec must preserve high platform resilience and maintain data sovereignty within Australia to protect the integrity of Australia’s financial markets. In this post, we explore how CommSec used AWS services to build a resilient, high-performing trading platform while meeting strict regulatory requirements and delivering an exceptional customer experience.

    Challenges of operating a multicloud environment

    In a pioneering move within CommBank, CommSec became the first critical workload to transition from on-premises data centers to the public cloud. In 2015, CommBank migrated CommSec’s web and mobile tier, and then migrated their application tier in 2019. As a leader and early cloud adopter, CommSec began with an active-active multicloud architecture to build confidence in the resilience of the public cloud, using the AWS Asia Pacific (Sydney) Region as one of its fault domains. Operating a multicloud environment presented several challenges. The complexity of maintaining two deployment pipelines, an operating model spanning two public cloud platforms, and a custom failover process requiring external witness capabilities created operational overhead. This reduced development velocity and engineering proficiency while maintaining a dependency on on-premises data centers. At the same time, the limited opportunity to use cloud-based services to keep parity and compatibility with both public clouds stifled innovation.

    Solution overview

    As AWS became CommBank’s preferred cloud provider, the CommSec team rearchitected its app, web, and mobile tiers in early 2025 to run entirely on AWS. With the move to AWS as their sole cloud provider, they took advantage of a new fault isolation boundary to establish a resilience posture similar to what they had with their multicloud solution, but with a simplified architecture.

    In the previous design, if an issue or outage occurred in a cloud provider or physical data center, traffic was routed and served through the alternate cloud. With the consolidation of the platform on AWS, the CommSec team decided on an Availability Zone as the new fault isolation boundary. Using Amazon Application Recovery Controller (ARC) zonal shift, they can perform a failover to minimize impact to the customer in case of infrastructure or application gray failures while satisfying the requirement to have a physical and logical isolation using multiple Availability Zones in a Region. ARC zonal shift was enabled on their load balancers, so the CommSec team could divert traffic away from an impaired Availability Zone without relying on control plane actions. The same ARC zonal shift capability is being used to help the CommSec team manage application gray failures by reducing customer impact when they occur.

    Consolidating on AWS and using ARC zonal shift to manage failures helped the CommSec team realize several important benefits:

    • Out-of-the-box failover capabilities with ARC zonal shift enabled the team to implement comprehensive and automated procedures to move traffic away from an Availability Zone.
    • Comprehensive playbooks that undergo regular validation exercises to verify the effectiveness of the failover procedures and operational readiness.
    • Standardized deployment pipelines and simplified configuration made operating system patching and code deployments two times faster.
    • They saw a 25% base capacity reduction by running the CommSec platform across three AWS Availability Zones compared to two stacks on each public cloud (four stacks) in the past, bringing down operational costs.

    The following diagram illustrates the solution architecture.

    The CommSec team introduced several resilience improvements:

    • With scale-in and scale-out happening multiple times a day, the process of scaling needed to be as resilient as possible. The CommSec team made sure the entire scale-out bootstrap process had no dependencies on external resources by storing and retrieving application binaries from Amazon Simple Storage Service (Amazon S3) buckets within the same AWS account.
    • Because traffic patterns are incredibly spiky, especially during market open (CommSec traffic often increases threefold between 9:59-10:02 AM on market open), the team implemented Load balancer Capacity Unit (LCU) reservations on the web tier load balancers. This provided sufficient Application Load Balancer (ALB) capacity at the start of the trading day without having to rely on reactive scaling for this predictable spike.
    • They implemented ALB health checks for hard failures to automatically remove instances from target groups. Traffic will shift away from the targets when health checks fail, with alerts signaling the operational team to investigate and remediate.
    • New AWS Direct Connect connections from AWS to the Australian Liquidity Centre (which hosts the Australian Stock Exchange (ASX)’s primary trading, clearing, and settlement systems) were established to improve the reliability of the connectivity to financial markets, including ASX and CBOE exchanges.

    ARC zonal shift to help mitigate impairments

    In 2023, AWS launched zonal shift, part of Amazon Application Recovery Controller. With zonal shift, you can shift application traffic away from an Availability Zone in a highly available manner for supported resources. This action helps quickly recover an application when an Availability Zone experiences an impairment, reducing the duration and severity of impact to the application due to events such as power outages and hardware or software failures. Zonal shift supports Application and Network Load Balancers, Amazon EC2 Auto Scaling Groups, and Amazon Elastic Kubernetes Service (Amazon EKS).

    The CommSec team enabled ARC zonal shift on their ALBs for their web and application tier with cross-zone load balancing enabled. When started, zonal shift takes two actions. First, it removes the IP address of the load balancer node in the specified Availability Zone from DNS, so new queries won’t resolve to that endpoint. This stops future client requests from being sent to that node. Second, it instructs the load balancer nodes in the other Availability Zones not to route requests to targets in the impaired Availability Zone. Cross-zone load balancing is still used in the remaining Availability Zones during the zonal shift, as shown in the following figure.

    After the issue is resolved and the application is available again in all Availability Zones, the CommSec team cancels the zonal shift, and traffic is redistributed across all three Availability Zones.

    Benefits of ARC zonal shift

    ARC zonal shift helps organizations maintain higher availability SLAs, reduce operational costs associated with multi-step manual failover procedures, and minimize revenue loss from service disruptions. The straightforward nature of ARC zonal shift helps teams conduct frequent, on-demand, low-risk testing of their Availability Zone evacuation procedures. The ability to perform regular validation makes sure failover processes remain reliable and builds organizational confidence in disaster recovery capabilities.

    “ARC zonal shift is the most efficient way for CommSec to use AWS services whilst meeting our resilience requirements. It provided an out-of-the-box solution that was easier than trying to implement an Availability Zone recovery solution ourselves. Hopefully it’s something we will never need, but our regular resilience testing ensures it’s there and will work if we ever need it.”

    – Henry Zhao, CommBank Staff Software Engineer.

    Conclusion

    By using AWS services and implementing a robust Multi-AZ architecture, the CommSec trading platform continues to meet the demanding needs of Australia’s leading online broker. The combination of ARC zonal shift capabilities, optimized load balancer configurations, and comprehensive runbooks and operational procedures has enabled CommSec to maintain exceptional reliability while serving over millions of customers. CommSec’s journey showcases how careful architectural decisions and AWS managed services can help organizations achieve both operational excellence and superior customer experience for mission-critical financial applications.

    To learn more, refer to AWS Fault Isolation Boundaries and Amazon Application Recovery Controller.


    About the authors

    AWS Weekly Roundup: AWS Developer Day, Trust Center, Well-Architected for Enterprises, and more (Feb 17, 2025)

    Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-developer-day-trust-center-well-architected-for-enterprises-and-more-feb-17-2025/

    Join us for the AWS Developer Day on February 20! This virtual event is designed to help developers and teams incorporate cutting-edge yet responsible generative AI across their development lifecycle to accelerate innovation.

    In his keynote, Jeff Barr, Vice President of AWS Evangelism, shares his thoughts on the next generation of software development based on generative AI, the skills needed to thrive in this changing environment, and how he sees it evolving in the future.

    Get a first look at exciting technical deep-dive and product updates about Amazon Q Developer, AWS Amplify, and GitLab Duo with Amazon Q. You get the chance to explore real-world use cases, live coding demos, interactive sessions, and community spotlight sessions with Christian Bonzelet (AWS Community Builder), Hazel Saenz (AWS Serverless Hero), Matt Lewis (AWS Data Hero), and Johannes Koch (AWS DevTools Hero). Please sign up for this event now!

    Last week’s launches
    Here are some launches that got my attention:

    Updating AWS SDK defaults for AWS STS – As we shared upcoming changes to the AWS Security Token Service (AWS STS) global endpoint to improve the resiliency and performance of your applications, we’re updating two defaults of AWS Software Development Kits (AWS SDKs) and AWS Command Line Interfaces (AWS CLIs) on July 31st 2025 – the default AWS STS service to regional, and the default retry strategy to standard. We recommend that you test your application before the release to avoid an unexpected experience after updating.

    Introducing the AWS Trust CenterChris Betz, CISO at Amazon Web Services (AWS), shared AWS Trust Center, a new online resource communicating how we approach securing your assets in the cloud. This resource is a window into our security practices, compliance programs, and data protection controls that demonstrates how we work to earn your trust every day.

    AWS CloudTrail network activity events for VPC endpoint – This feature provides you with a powerful tool to enhance your security posture, detect potential threats, and gain deeper insights into your VPC network traffic. This feature addresses your critical needs for comprehensive visibility and control over your AWS environments.

    AWS Verified Access support for non-HTTP resources – AWS Verified Access now extends beyond HTTP apps to provide VPN-less, secure access to non-HTTP resources like Amazon Relational Database Service (Amazon RDS) databases, enabling improved security and enhanced user experience for both web applications and database connections. To learn more, visit the Verified Access endpoints page and a video tutorial.

    New subnet management of Network Load Balancer (NLB) – NLBs were previously restricted to only adding subnets in new Availability Zones, and they now support full subnet management, including removal of subnets, matching the capabilities of Application Load Balancer (ALB). This enhancement offers organizations greater control over their network architecture and brings consistency to AWS load balancing services.

    Meta SAM 2.1 and Falcon 3 models in Amazon SageMaker JumpStart – You can use Meta’s Segment Anything Model (SAM) 2.1 with state-of-the-art video and image segmentation capabilities in a single model. You can also use the Falcon 3 family with five models ranging from 1 to 10 billion parameters, with a focus on enhancing science, math, and coding capabilities. To learn more, visit SageMaker JumpStart pretrained models and Getting started with Amazon SageMaker JumpStart.

    For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

    Other AWS news
    Here are some additional news items that you might find interesting:

    AWS Documentation updateGreg Wilson, a lead of AWS Documentation, SDK, and CLI teams shared an insightful blog post about the progress, challenges, and what’s next for technical documentation for 200+ AWS services. It includes AWS Decision Guides for choosing the right service for specific needs; optimizing documents for readability, such as doubled code samples; and improving usability, such as dark mode and auto-suggest with top global navigation controls. You can also learn about how we use generative AI to help create technical documents.

    AWS Well-Architected for Enterprises – This is a new free digital course designed for technical professionals who architect, build, and operate AWS solutions at scale. This intermediate-level course will help you optimize your cloud architecture while aligning to your business goals. The course takes approximately 1 hour to complete and includes a knowledge check at the end to reinforce your learning.

    Integrating AWS with .NET Aspire – The .NET team at AWS has been working on integrations for connecting your .NET applications to AWS resources. Learn about how to automatically deploy AWS application resources using Aspire.Hosting.AWS NuGet package for NET Aspire, an open source framework building cloud-ready applications.

    Upcoming AWS events
    Check your calendars and sign up for these upcoming AWS events:

    AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations. Available in multiple geographic regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

    AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

    AWS GenAI Lofts – GenAI Lofts offer collaborative spaces and immersive experiences for startups and developers. You can join in-person GenAI Loft San Francisco events such as Built on Amazon Bedrock demo nights (April 19), SageMaker Unified Studio Demo for Startups (April 21), and Hands-on with Agentic Graph RAG Workshop (April 25). GenAI Loft Berlin has its Opening Day on February 24 and goes to March 7.

    AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Karachi, Pakistan (February 22), Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czeh Republic (April 29).

    AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity. You can subscribe for event updates now!

    You can browse all upcoming in-person and virtual events.

    That’s all for this week. Check back next Monday for another Weekly Roundup!

    Channy

    This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

    Top Architecture Blog Posts of 2024

    Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

    Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

    AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

    (By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

    Without further ado, here are our top posts from 2024!

    #10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

    This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

    Architecture for deploying stable diffusion on ComfyUI

    Figure 1. Architecture for deploying stable diffusion on ComfyUI

    #9 Let’s Architect! Designing Well-Architected systems

    In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

    Let's Architect

    Figure 2. Let’s Architect

    #8 Let’s Architect! Learn About Machine Learning on AWS

    As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

    Let's Architect

    Figure 3. Let’s Architect

    If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

    #7 Creating an organizational multi-Region failover strategy

    Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

    When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

    Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

    #6 Building a three-tier architecture on a budget

    Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

    Example of a three-tier architecture on AWS

    Figure 5. Example of a three-tier architecture on AWS

    #5 Announcing updates to the AWS Well-Architected Framework guidance

    As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

    Well-Architected logo

    Figure 6. Well-Architected logo

    #4 Let’s Architect! Serverless developer experience in AWS

    One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

    Let's Architect

    Figure 7. Let’s Architect

    #3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

    This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

    Chaos engineering pattern for hybrid architecture (3-tier application)

    Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

    #2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

    Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

    Well-Architected logo

    Figure 9. Well-Architected logo

    #1 How an insurance company implements disaster recovery of 3-tier applications

    And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

    The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

    Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

    Thank you!

    As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

    For other top post lists, see our Top 10 and Top 5 posts from previous years.

    How an insurance company implements disaster recovery of 3-tier applications

    Post Syndicated from Amit Narang original https://aws.amazon.com/blogs/architecture/how-an-insurance-company-implements-disaster-recovery-of-3-tier-applications/

    A good strategy for resilience will include operating with high availability and planning for business continuity. It also accounts for the incidence of natural disasters, such as earthquakes or floods and technical failures, such as power failure or network connectivity. AWS recommends a multi-AZ strategy for high availability and a multi-Region strategy for disaster recovery. In this post, we explore how one of our customers, a US-based insurance company, uses cloud-native services to implement the disaster recovery of 3-tier applications.

    At this insurance company, a relevant number of critical applications are 3-tier Java or .Net applications. These applications require access to IBM DB2, Oracle, or Microsoft SQLServer databases that run on Amazon EC2 instances. The requirement was to create a disaster recovery strategy that implements a Pilot Light or Warm/Standby scenario. This design needs to keep costs at a minimum, and it needs to allow for failure detection and manual failover of resources. Furthermore, it needs to keep the Recovery Time Objective (RTO) and the Recovery Point Objective (RPO) under 15 minutes. Finally, the solution could not use any public resources.

    The solution

    Amazon Route53 Application Recovery Controller (Route53 ARC) helps manage and orchestrate application failover and recovery across multiple AWS Regions or on-premises environments. It is specifically focused on managing DNS routing and traffic management during failover and recovery operation; however, some customers decide to implement their own strategies for application recovery. In this blog, we are going to focus on how one of our financial services customer implements it.

    The Well-Architected framework explains that a good disaster recovery plan needs to manage configuration drift. A good practice is to use the delivery pipeline to deploy to both Regions and to regularly test the recovery pattern. There are customers that go a step further and even choose to operate in the secondary Region for a period of time.

    The solution chosen by one of our leading insurance customers encompasses two distinct scenarios: a failover and a failback scenario. The failover scenario covers a list of steps to failover applications from the primary Region to the secondary Region. The failback process is the return of the operations to the primary Region.

    Failover

    Our customer decided to test the Pilot Light scenario. This scenario considers an application and a database deployed both in the primary and secondary Regions. As a requirement to achieve the 15-minute RPO, an application deployed in the primary Region needs to replicate data to the secondary Region. This async replication is implemented for each of the company’s database engines (DB2, SQLServer, Oracle) using native tooling. Leveraging native tooling was an existing practice and going with it would help minimize any operational impact.

    It is important to notice that the detection and failover mechanisms is created in the secondary Region. This ensures these components will remain available when the primary Region becomes unavailable. Another important aspect is to establish connectivity between the two networks. This is needed to allow for the database replication.

    The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

    Figure 1. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

    The failover procedure uses the following steps for detection and failover:

    1. An Amazon EventBridge scheduler runs the AWS Lambda function every 60 seconds.
    2. The Lambda function tests the application endpoint and adds a custom metric to Amazon CloudWatch. If the application is unavailable, a CloudWatch Alarm will start the Lambda Function that initiates the failover.
    3. A Lambda function initiates the failover by starting a Jenkins pipeline. The pipeline will failover the application and the database to the secondary Region. The Jenkins pipeline starts with a manual approval step, ensuring that the failover process does not start automatically.
    4. Once approvers validate the necessity of the failover, they approve the workflow, and the pipeline moves to the next stage.
    5. The pipeline failovers the database, promoting the database in the secondary Region to the primary state and enables write operations.
    6. Next, start or scale out application servers that run on EC2 instances or containers. This is important to assure they will support the increased load in the secondary Region once failover is complete.
    7. At this point, database and application servers are ready to receive load. Next, the Application Load Balancer (ALB) needs to failover to the secondary Region. Route53 failover routing policy automatically failovers between Regions, but this customer wanted to manually control this step using a health check. To implement a manual failover of the ALB, the pipeline creates a file in a designated S3 bucket. A Lambda function regularly checks if this file exists in the expected location. If so, it triggers a CloudWatch Alarm and the Route53 health check will fail. At this point, Route 53 will redirect traffic to the ALB in the secondary Region, becoming the new active endpoint.

    Failback

    The failback scenario starts when all the required services become online in the primary Region. AWS recommends using AWS Personal Health Dashboard to check for service health. Figure 2 illustrates the failback process in detail. It shows the step-by-step flow from initiating the failback procedure to the final DNS switchover, highlighting the key components and interactions involved in each stage. This visual representation helps to clarify the complex process of returning operations to the primary Region.

    Diagram of the failback process

    Figure 2. Diagram of the failback process

    The failback procedure is implemented in six steps:

    1. A cloud operator or Site Reliability Engineer (SRE) initiates the failback procedure by submitting a form on an HTML page. A Lambda function starts a Jenkins pipeline.
    2. The pipeline initiates the delta sync replication of the database. This ensures that data changes made in the secondary Region are replicated to the primary Region.
    3. The next stage is a manual approval to recover back to the primary Region, where the SRE verifies that the databases are in sync and all services needed are online in the primary Region.
    4. Upon approval, the pipeline starts the application servers in the primary Region.
    5. Next, the database in the primary Region is promoted for write operations. The database endpoint in the secondary Region is updated to point to the primary Region’s database.
    6. As explained in the failover section, the DNS switchover depends on a file existing in S3. Since this file was created for our failover event, the pipeline will now remove this file. The Lambda function identifies the change and updates the state of the CloudWatch Alarm, then the Route53 Healthcheck will change the state. At this point, the ALB in the primary Region becomes active and failback completes successfully.

    Benefits

    This customer identified the following benefits in implementing this design:

    • Customizable solution that aligns with the company’s internal processes, operating model, and technologies in use
    • Standardized pattern applicable across the organization for applications with different technologies, including databases, Windows and Linux applications running on EC2
    • Recovery Point Objective (RPO) and Recovery Time Objective (RTO) of less than 15 minutes
    • A cost optimized solution that uses cloud native services to implement the detection and failover scenarios

    Conclusion

    The solution for the disaster recovery of 3-tier applications demonstrates this financial services customer’s commitment to ensuring business continuity and resilience. This design showcases the company’s ability to tailor their architecture to their specific requirements. Achieving an RPO and RTO of less than 15 minutes for critical applications is a remarkable feat. It ensures minimal disruption to business operations during regional outages.

    Furthermore, this solution leverages existing technologies and processes within the company, allowing for seamless integration and adoption across the organization. The ability to standardize this pattern for applications with different technologies helps simplifying the operating model.

    If you’re an enterprise seeking to enhance the resilience of your critical applications, this disaster recovery solution from one of our enterprise customers serves as an inspiring example. To further explore the disaster recovery strategies and best practices on AWS, we recommend the following resources:

    AWS Weekly Roundup: What’s App, AWS Lambda, Load Balancers, AWS Console, and more (Oct 14, 2024).

    Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-whats-app-aws-lambda-load-balancers-aws-console-and-more-oct-14-2024/

    Last week, AWS hosted free half-day conferences in London and Paris. My colleagues and I demonstrated how developers can use generative AI tools to speed up their design, analysis, code writing, debugging, and deployment workflows. These events were held at the GenAI Lofts. These lofts are open until October 25 (London) and November 5 (Paris). They will be packed with events, conferences, workshops, and meetups. If you’re around, be sure to check the agenda (London, Paris).

    The AWS team at the NGDE day in London Veliswa live coding on stage at NGDE Day London

    Our well-known AWS News blog co-author Veliswa did an amazing demo. She live-coded a Duolingo-like app from scratch, just using suggestions and reviews from Amazon Q Developer.

    Now, let’s turn to other exciting news in the AWS universe from last week.

    Last week’s launches
    Here are some launches that got my attention:

    Bring your conversations to WhatsAppAWS has added support for What’sApp to AWS End User Messaging, so developers can reach users on WhatsApp with multimedia and interactive messaging options. This feature integrates with SMS and push notifications already available. Developers can get started quickly using AWS Management Console.

    Amazon Redshift data sharing with data lake tables — This offers a secure and convenient way to share live data lake tables across different Amazon Redshift warehouses. Data sharing of data lake tables in AWS Glue Data Catalog provides live access to the data, so you always see the most up-to-date and consistent information as it’s updated in the data lake.

    Zonal shift and zonal autoshift for cross zoned Network Load BalancerNetwork Load Balancer (NLB) now supports the Amazon Application Recovery Controller zonal shift and zonal autoshift features on load balancers that are enabled across zones. With Zonal shift, you can quickly shift traffic away from an impaired Availability Zone and recover from events such as bad application deployment and gray failures. Zonal autoshift safely and automatically shifts your traffic away from an Availability Zone when AWS identifies a potential impact to it.

    Console to Code to generate infrastructure as a service code — This is by far my favorite launch of the week. Console to Code makes it simple, fast, and cost-effective to move from prototyping in the AWS Management Console to building code for production deployments. You can generate code for their console actions in their preferred format with a single click. The generated code helps you get started and bootstrap your automation pipelines for tasks. Console to Code is powered by Amazon Q Developer.

    A new getting started experience for AWS CodePipelineAWS Data Pipeline introduces a simplified and new getting started experience so you can quickly create new pipelines. When you create a new pipeline using the CodePipeline console, you can now select from a list of pipeline templates across build, automation, and deployment use cases. After selecting a pipeline template, you will be prompted to enter values for the action configuration fields in the pipeline definition, and completing the process will render a fully configured pipeline that’s ready to run.

    AWS Lambda detects and stops recursive loops between Lambda and Amazon S3 — Lambda recursive loop detection can now automatically detect and stop recursive loops between AWS Lambda and Amazon Simple Storage Service (Amazon S3). Lambda recursive loop detection, which is enabled by default, is a preventative guardrail that automatically detects and stops recursive invocations between Lambda and other supported services, preventing unintended usage and billing from runaway workloads.

    Amazon MemoryDB for ValkeyAmazon MemoryDB for Redis is a fully managed, Valkey– and Redis OSS-compatible database service, which provides multi-AZ durability, microsecond read and single-digit millisecond write latency, and high throughput. It is ideal for use cases such as caching, leaderboards, and session stores. With MemoryDB for Valkey, you can benefit from a fully managed experience built on open-source technology while using the security, operational excellence, and reliability that AWS provides. MemoryDB for Valkey also delivers the fastest vector search performance at the highest recall rates among popular vector databases on AWS.

    Amazon Polly adds four wew English voices for the generative engine and expands to three RegionsPolly is a managed service that turns text into lifelike speech, so you can create applications that talk and to build speech-enabled products depending on your business needs. The generative engine is the most advanced Amazon Polly text-to-speech (TTS) model. With this launch, we add a variety of new synthetic generative English voices to the Amazon Polly portfolio: an Australian English voice Olivia and three US English voices Joanna, Danielle, and Stephen. These voices have more natural pronunciation and prosody. You can use this high-tier product in various industries and for different purposes such as education, publishing, or marketing.

    For a full list of AWS announcements, be sure to keep an eye on the AWS What’s New Feed page.

    Upcoming AWS events
    Check your calendars and sign up for these AWS events:

    AWS Cloud Day Prague — Join us for a free technical conferences in Prague on October 23. I will be there and share with attendees “The Art of Transforming a Foundation Model into a Domain Expert”. Be sure to register today!

    Innovate Migrate, Modernize, and Build Whether you are new to the cloud or an experienced user, you will learn something new at AWS Innovate. This is a free online conference. Register for a time and region convenient to North America (October 15), or Europe, Middle East & Africa (October 24).

    AWS Community Days Join community-led conferences featuring technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Don’t miss out on the AWS Community Days happening on October 19 in Vadodara, Spain, and Guatemala.

    AWS re:Invent 2024 Registration is now open for the annual tech extravaganza, taking place December 2 – 6 in Las Vegas. Beside recording podcast episodes, I will present three sessions:

    • CMP410 | Accelerate testing cycles of CI/CD pipelines with EC2 Mac instances (with Vishal)
    • DEV301 | The art of transforming foundation models into domain experts (with Gregory)
    • DEV334 | Swift, server-side, serverless

    There are just a few seats left for these three sessions, so be sure to book your seat today!

    Browse more upcoming AWS led in-person and virtual events and developer-focused events.

    That’s all for this week. Check back next Monday for another Weekly Roundup!

    — seb

    This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

    AWS Weekly Roundup – Application Load Balancer IPv6, Amazon S3 pricing update, Amazon EC2 Flex instances, and more (May 20, 2024)

    Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-application-load-balancer-ipv6-amazon-s3-pricing-update-amazon-ec2-flex-instances-and-more-may-20-2024/

    AWS Summit season is in full swing around the world, with last week’s events in Bengaluru, Berlin, and  Seoul, where my blog colleague Channy delivered one of the keynotes.

    AWS Summit Seoul Keynote

    Last week’s launches
    Here are some launches that got my attention:

    Amazon S3 will no longer charge for several HTTP error codesA customer reported how he was charged for Amazon S3 API requests he didn’t initiate and which resulted in AccessDenied errors. The Amazon Simple Storage Service (Amazon S3) service team updated the service to not charge such API requests anymore. As always when talking about pricing, the exact wording is important, so please read the What’s New post for the details.

    Introducing Amazon EC2 C7i-flex instances – These instances delivers up to 19 percent better price performance compared to C6i instances. Using C7i-flex instances is the easiest way for you to get price performance benefits for a majority of compute-intensive workloads. The new instances are powered by the 4th generation Intel Xeon Scalable custom processors (Sapphire Rapids) that are available only on AWS and offer 5 percent lower prices compared to C7i.

    Application Load Balancer launches IPv6 only support for internet clientsApplication Load Balancer now allows customers to provision load balancers without IPv4s for clients that can connect using just IPv6s. To connect, clients can resolve AAAA DNS records that are assigned to Application Load Balancer. The Application Load Balancer is still dual stack for communication between the load balancer and targets. With this new capability, you have the flexibility to use both IPv4s or IPv6s for your application targets while avoiding IPv4 charges for clients that don’t require it.

    Amazon VPC Lattice now supports TLS Passthrough – We announced the general availability of TLS passthrough for Amazon VPC Lattice, which allows customers to enable end-to-end authentication and encryption using their existing TLS or mTLS implementations. Prior to this launch, VPC Lattice supported HTTP and HTTPS listener protocols only, which terminates TLS and performs request-level routing and load balancing based on information in HTTP headers.

    Amazon DocumentDB zero-ETL integration with Amazon OpenSearch Service – This new integration provides you with advanced search capabilities, such as fuzzy search, cross-collection search and multilingual search, on your Amazon DocumentDB (with MongoDB compatibility) documents using the OpenSearch API. With a few clicks in the AWS Management Console, you can now synchronize your data from Amazon DocumentDB to Amazon OpenSearch Service, eliminating the need to write any custom code to extract, transform, and load the data.

    Amazon EventBridge now supports customer managed keys (CMK) for event buses – This capability allows you to encrypt your events using your own keys instead of an AWS owned key (which is used by default). With support for CMK, you now have more fine-grained security control over your events, satisfying your company’s security requirements and governance policies.

    For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

    Other AWS news
    Here are some additional news items, open source projects, and Twitch shows that you might find interesting:

    The Four Pillars of Managing Email Reputation – Dustin Taylor is the manager of anti-abuse and email deliverability for Amazon Simple Email Service (SES). He wrote a remarkable post exploring Amazon SES approach to managing domain and IP reputation. Maintaining a high reputation ensures optimal recipient inboxing. His post outlines how Amazon SES protects its network reputation to help you deliver high-quality email consistently. A worthy read, even if you’re not sending email at scale. I learned a lot.

    AWS Build On Generative AIBuild On Generative AI – Season 3 of your favorite weekly Twitch show about all things generative artificial intelligence (AI) is in full swing! Streaming every Monday, 9:00 AM US PT, my colleagues Tiffany and Darko discuss different aspects of generative AI and invite guest speakers to demo their work.

    AWS open source news and updates – My colleague Ricardo writes this weekly open source newsletter, in which he highlights new open source projects, tools, and demos from the AWS Community.

    Upcoming AWS events

    AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Hong Kong (May 22), Milan (May 23), Stockholm (June 4), and Madrid (June 5).

    AWS re:Inforce – Explore 2.5 days of immersive cloud security learning in the age of generative AI at AWS re:Inforce, June 10–12 in Pennsylvania.

    AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Midwest | Columbus (June 13), Sri Lanka (June 27), Cameroon (July 13), Nigeria (August 24), and New York (August 28).

    Browse all upcoming AWS led in-person and virtual events and developer-focused events.

    That’s all for this week. Check back next Monday for another Weekly Roundup!

    — seb

    This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

    AWS Weekly Roundup — Happy Lunar New Year, IaC generator, NFL’s digital athlete, AWS Cloud Clubs, and more — February 12, 2024

    Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-happy-lunar-new-year-iac-generator-nfls-digital-athlete-aws-cloud-clubs-and-more-february-12-2024/

    Happy Lunar New Year! Wishing you a year filled with joy, success, and endless opportunities! May the Year of the Dragon bring uninterrupted connections and limitless growth 🐉 ☁

    In case you missed it, here’s outstanding news you need to know as you plan your year in early 2024.

    AWS was named as a Leader in the 2023 Magic Quadrant for Strategic Cloud Platform Services. AWS is the longest-running Magic Quadrant Leader, with Gartner naming AWS a Leader for the thirteenth consecutive year. See Sebastian’s blog post to learn more. AWS has been named a Leader for the ninth consecutive year in the 2023 Gartner Magic Quadrant for Cloud Database Management Systems, and we have been positioned highest for ability to execute by providing a comprehensive set of services for your data foundation across all workloads, use cases, and data types. See Rahul Pathak’s blog post to learn more.

    AWS also has been named a Leader in data clean room technology according to the IDC MarketScape: Worldwide Data Clean Room Technology 2024 Vendor Assessment (January 2024). This report evaluated data clean room technology vendors for use cases across industries. See the AWS for Industries Blog channel post to learn more.

    Last Week’s Launches
    Here are some launches that got my attention:

    A new Local Zone in Houston, Texas – Local Zones are an AWS infrastructure deployment that places compute, storage, database, and other select services closer to large population, industry, and IT centers where no AWS Region exists. AWS Local Zones are available in the US in 15 other metro areas and globally in an additional 17 metros areas, allowing you to deliver low-latency applications to end users worldwide. You can enable the new Local Zone in Houston (us-east-1-iah-2a) from the Zones tab in the Amazon EC2 console settings.

    AWS CloudFormation IaC generator – You can generate a template using AWS resources provisioned in your account that are not already managed by CloudFormation. With this launch, you can onboard workloads to Infrastructure as Code (IaC) in minutes, eliminating weeks of manual effort. You can then leverage the IaC benefits of automation, safety, and scalability for the workloads. Use the template to import resources into CloudFormation or replicate resources in a new account or Region. See the user guide and blog post to learn more.

    A new look-and-feel of Amazon Bedrock console – Amazon Bedrock now offers an enhanced console experience with updated UI improves usability, responsiveness, and accessibility with more seamless support for dark mode. To get started with the new experience, visit the Amazon Bedrock console.

    2024-bedrock-visual-refresh

    One-click WAF integration on ALB – Application Load Balancer (ALB) now supports console integration with AWS WAF that allows you to secure your applications behind ALB with a single click. This integration enables AWS WAF protections as a first line of defense against common web threats for your applications that use ALB. You can use this one-click security protection provided by AWS WAF from the integrated services section of the ALB console for both new and existing load balancers.

    Up to 49% price reduction for AWS Fargate Windows containers on Amazon ECS – Windows containers running on Fargate are now billed per second for infrastructure and Windows Server licenses that their containerized application requests. Along with the infrastructure pricing for on-demand, we are also reducing the minimum billing duration for Windows containers to 5 minutes (from 15 minutes) for any Fargate Windows tasks starting February 1st, 2024 (12:00am UTC). The infrastructure pricing and minimum billing period changes will automatically reflect in your monthly AWS bill. For more information on the specific price reductions, see our pricing page.

    Introducing Amazon Data Firehose – We are renaming Amazon Kinesis Data Firehose to Amazon Data Firehose. Amazon Data Firehose is the easiest way to capture, transform, and deliver data streams into Amazon S3, Amazon Redshift, Amazon OpenSearch Service, Splunk, Snowflake, and other 3rd party analytics services. The name change is effective in the AWS Management Console, documentations, and product pages.

    AWS Transfer Family integrations with Amazon EventBridge – AWS Transfer Family now enables conditional workflows by publishing SFTP, FTPS, and FTP file transfer events in near real-time, SFTP connectors file transfer event notifications, and Applicability Statement 2 (AS2) transfer operations to Amazon EventBridge. You can orchestrate your file transfer and file-processing workflows in AWS using Amazon EventBridge, or any workflow orchestration service of your choice that integrates with these events.

    For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

    Other AWS News
    Some other updates and news that you might have missed:

    NFL’s digital athlete in the Super Bowl – AWS is working with the National Football League (NFL) to take player health and safety to the next level. Using AI and machine learning, they are creating a precise picture of each player in training, practice, and games. You could see this technology in action, especially with the Super Bowl on the last Sunday!

    Amazon’s commiting the responsible AI – On February 7, Amazon joined the U.S. Artificial Intelligence Safety Institute Consortium, established by the National Institute of Standards of Technology (NIST), to further our government and industry collaboration to advance safe and secure artificial intelligence (AI). Amazon will contribute compute credits to help develop tools to evaluate AI safety and help the institute set an interoperable and trusted foundation for responsible AI development and use.

    Compliance updates in South Korea – AWS has completed the 2023 South Korea Cloud Service Providers (CSP) Safety Assessment Program, also known as the Regulation on Supervision on Electronic Financial Transactions (RSEFT) Audit Program. AWS is committed to helping our customers adhere to applicable regulations and guidelines, and we help ensure that our financial customers have a hassle-free experience using the cloud. Also, AWS has successfully renewed certification under the Korea Information Security Management System (K-ISMS) standard (effective from December 16, 2023, to December 15, 2026).

    Join AWS Cloud Clubs CaptainsAWS Cloud Clubs are student-led user groups for post-secondary level students and independent learners. Interested in founding or co-founding a Cloud Club in your university or region? We are accepting applications from February 5-18, 2024.

    Upcoming AWS Events
    Check your calendars and sign up for upcoming AWS events:

    AWS Innovate AI/ML and Data Edition – Join our free online conference to learn how you and your organization can leverage the latest advances in generative AI. You can register upcoming AWS Innovate Online event that fits your timezone in Asia Pacific & Japan (February 22), EMEA (February 29), and Americas (March 14).

    AWS Public Sector events – Join us at the AWS Public Sector Symposium Brussels (March 12) to discover how the AWS Cloud can help you improve resiliency, develop sustainable solutions, and achieve your mission. AWS Public Sector Day London (March 19) gathers professionals from government, healthcare, and education sectors to tackle pressing challenges in United Kingdom public services.

    Kicking off AWS Global Summits – AWS Summits are a series of free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Below is a list of available AWS Summit events taking place in April:

    You can browse all upcoming AWS-led in-person and virtual events, and developer-focused events such as AWS DevDay.

    That’s all for this week. Check back next Monday for another Week in Review!

    — Channy

    This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

    Zonal autoshift – Automatically shift your traffic away from Availability Zones when we detect potential issues

    Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/zonal-autoshift-automatically-shift-your-traffic-away-from-availability-zones-when-we-detect-potential-issues/

    Today we’re launching zonal autoshift, a new capability of Amazon Route 53 Application Recovery Controller that you can enable to automatically and safely shift your workload’s traffic away from an Availability Zone when AWS identifies a potential failure affecting that Availability Zone and shift it back once the failure is resolved.

    When deploying resilient applications, you typically deploy your resources across multiple Availability Zones in a Region. Availability Zones are distinct groups of physical data centers at a meaningful distance apart (typically miles) to make sure that they have diverse power, connectivity, network devices, and flood plains.

    To help you protect against an application’s errors, like a failed deployment, an error of configuration, or an operator error, we introduced last year the ability to manually or programmatically trigger a zonal shift. This enables you to shift the traffic away from one Availability Zone when you observe degraded metrics in that zone. It does so by configuring your load balancer to direct all new connections to infrastructure in healthy Availability Zones only. This allows you to preserve your application’s availability for your customers while you investigate the root cause of the failure. Once fixed, you stop the zonal shift to ensure the traffic is distributed across all zones again.

    Zonal shift works at the Application Load Balancer (ALB) or Network Load Balancer (NLB) level only when cross-zone load balancing is turned off, which is the default for NLB. In a nutshell, load balancers offer two levels of load balancing. The first level is configured in the DNS. Load balancers expose one or more IP addresses for each Availability Zone, offering a client-side load balancing between zones. Once the traffic hits an Availability Zone, the load balancer sends traffic to registered healthy targets, typically an Amazon Elastic Compute Cloud (Amazon EC2) instance. By default, ALBs send traffic to targets across all Availability Zones. For zonal shift to properly work, you must configure your load balancers to disable cross-zone load balancing.

    When zonal shift starts, the DNS sends all traffic away from one Availability Zone, as illustrated by the following diagram.

    ARC Zonal Shift

    Manual zonal shift helps to protect your workload against errors originating from your side. But when there is a potential failure in an Availability Zone, it is sometimes difficult for you to identify or detect the failure. Detecting an issue in an Availability Zone using application metrics is difficult because, most of the time, you don’t track metrics per Availability Zone. Moreover, your services often call dependencies across Availability Zone boundaries, resulting in errors seen in all Availability Zones. With modern microservice architectures, these detection and recovery steps must often be performed across tens or hundreds of discrete microservices, leading to recovery times of multiple hours.

    Customers asked us if we could take the burden off their shoulders to detect a potential failure in an Availability Zone. After all, we might know about potential issues through our internal monitoring tools before you do.

    With this launch, you can now configure zonal autoshift to protect your workloads against potential failure in an Availability Zone. We use our own AWS internal monitoring tools and metrics to decide when to trigger a network traffic shift. The shift starts automatically; there is no API to call. When we detect that a zone has a potential failure, such as a power or network disruption, we automatically trigger an autoshift of your infrastructure’s NLB or ALB traffic, and we shift the traffic back when the failure is resolved.

    Obviously, shifting traffic away from an Availability Zone is a delicate operation that must be carefully prepared. We built a series of safeguards to ensure we don’t degrade your application availability by accident.

    First, we have internal controls to ensure we shift traffic away from no more than one Availability Zone at a time. Second, we practice the shift on your infrastructure for 30 minutes every week. You can define blocks of time when you don’t want the practice to happen, for example, 08:00–18:00, Monday through Friday. Third, you can define two Amazon CloudWatch alarms to act as a circuit breaker during the practice run: one alarm to prevent starting the practice run at all and one alarm to monitor your application health during a practice run. When either alarm triggers during the practice run, we stop it and restore traffic to all Availability Zones. The state of application health alarm at the end of the practice run indicates its outcome: success or failure.

    According to the principle of shared responsibility, you have two responsibilities as well.

    First you must ensure there is enough capacity deployed in all Availability Zones to sustain the increase of traffic in remaining Availability Zones after traffic has shifted. We strongly recommend having enough capacity in remaining Availability Zones at all times and not relying on scaling mechanisms that could delay your application recovery or impact its availability. When zonal autoshift triggers, AWS Auto Scaling might take more time than usual to scale your resources. Pre-scaling your resource ensures a predictable recovery time for your most demanding applications.

    Let’s imagine that to absorb regular user traffic, your application needs six EC2 instances across three Availability Zones (2×3 instances). Before configuring zonal autoshift, you should ensure you have enough capacity in the remaining Availability Zones to absorb the traffic when one Availability Zone is not available. In this example, it means three instances per Availability Zone (3×3 = 9 instances with three Availability Zones in order to keep 2×3 = 6 instances to handle the load when traffic is shifted to two Availability Zones).

    In practice, when operating a service that requires high reliability, it’s normal to operate with some redundant capacity online for eventualities such as customer-driven load spikes, occasional host failures, etc. Topping up your existing redundancy in this way both ensures you can recover rapidly during an Availability Zone issue but can also give you greater robustness to other events.

    Second, you must explicitly enable zonal autoshift for the resources you choose. AWS applies zonal autoshift only on the resources you chose. Applying a zonal autoshift will affect the total capacity allocated to your application. As I just described, your application must be prepared for that by having enough capacity deployed in the remaining Availability Zones.

    Of course, deploying this extra capacity in all Availability Zones has a cost. When we talk about resilience, there is a business tradeoff to decide between your application availability and its cost. This is another reason why we apply zonal autoshift only on the resources you select.

    Let’s see how to configure zonal autoshift
    To show you how to configure zonal autoshift, I deploy my now-famous TicTacToe web application using a CDK script. I open the Route 53 Application Recovery Controller page of the AWS Management Console. On the left pane, I select Zonal autoshift. Then, on the welcome page, I select Configure zonal autoshift for a resource.

    Zonal autoshift - 1

    I select the load balancer of my demo application. Remember that currently, only load balancers with cross-zone load balancing turned off are eligible for zonal autoshift. As the warning on the console reminds me, I also make sure my application has enough capacity to continue to operate with the loss of one Availability Zone.

    Zonal autoshift - 2

    I scroll down the page and configure the times and days I don’t want AWS to run the 30-minute practice. At first, and until I’m comfortable with autoshift, I block the practice 08:00–18:00, Monday through Friday. Pay attention that hours are expressed in UTC, and they don’t vary with daylight saving time. You may use a UTC time converter application for help. While it is safe for you to exclude business hours at the start, we recommend configuring the practice run also during your business hours to ensure capturing issues that might not be visible when there is low or no traffic on your application. You probably most need zonal autoshift to work without impact at your peak time, but if you have never tested it, how confident are you? Ideally, you don’t want to block any time at all, but we recognize that’s not always practical.

    Zonal autoshift - 3

    Further down on the same page, I enter the two circuit breaker alarms. The first one prevents the practice from starting. You use this alarm to tell us this is not a good time to start a practice run. For example, when there is an issue ongoing with your application or when you’re deploying a new version of your application to production. The second CloudWatch alarm gives the outcome of the practice run. It enables zonal autoshift to judge how your application is responding to the practice run. If the alarm stays green, we know all went well.

    If either of these two alarms triggers during the practice run, zonal autoshift stops the practice and restores the traffic to all Availability Zones.

    Finally, I acknowledge that a 30-minute practice run will run weekly and that it might reduce the availability of my application.

    Then, I select Create.

    Zonal autoshift - 4And that’s it.

    After a few days, I see the history of the practice runs on the Zonal shift history for resource tab of the console. I monitor the history of my two circuit breaker alarms to stay confident everything is correctly monitored and configured.

    ARC Zonal Shift - practice run

    It’s not possible to test an autoshift itself. It triggers automatically when we detect a potential issue in an Availability Zone. I asked the service team if we could shut down an Availability Zone to test the instructions I shared in this post; they politely declined my request :-).

    To test your configuration, you can trigger a manual shift, which behaves identically to an autoshift.

    A few more things to know
    Zonal autoshift is now available at no additional cost in all AWS Regions, except for China and GovCloud.

    We recommend applying the crawl, walk, run methodology. First, you get started with manual zonal shifts to acquire confidence in your application. Then, you turn on zonal autoshift configured with practice runs outside of your business hours. Finally, you modify the schedule to include practice zonal shifts during your business hours. You want to test your application response to an event when you least want it to occur.

    We also recommend that you think holistically about how all parts of your application will recover when we move traffic away from one Availability Zone and then back. The list that comes to mind (although certainly not complete) is the following.

    First, plan for extra capacity as I discussed already. Second, think about possible single points of failure in each Availability Zone, such as a self-managed database running on a single EC2 instance or a microservice that leaves in a single Availability Zone, and so on. I strongly recommend using managed databases, such as Amazon DynamoDB or Amazon Aurora for applications requiring zonal shifts. These have built-in replication and fail-over mechanisms in place. Third, plan the switch back when the Availability Zone will be available again. How much time do you need to scale your resources? Do you need to rehydrate caches?

    You can learn more about resilient architectures and methodologies with this great series of articles from my colleague Adrian.

    Finally, remember that only load balancers with cross-zone load balancing turned off are currently eligible for zonal autoshift. To turn off cross-zone load balancing from a CDK script, you need to remove stickinessCookieDuration and add load_balancing.cross_zone.enabled=false on the target group. Here is an example with CDK and Typescript:

        // Add the auto scaling group as a load balancing
        // target to the listener.
        const targetGroup = listener.addTargets('MyApplicationFleet', {
          port: 8080,
          // for zonal shift, stickiness & cross-zones load balancing must be disabled
          // stickinessCookieDuration: Duration.hours(1),
          targets: [asg]
        });    
        // disable cross zone load balancing
        targetGroup.setAttribute("load_balancing.cross_zone.enabled", "false");

    Now it’s time for you to select your applications that would benefit from zonal autoshift. Start by reviewing your infrastructure capacity in each Availability Zone and then define the circuit breaker alarms. Once you are confident your monitoring is correctly configured, go and enable zonal autoshift.

    — seb

    Security at multiple layers for web-administered apps

    Post Syndicated from Guy Morton original https://aws.amazon.com/blogs/security/security-at-multiple-layers-for-web-administered-apps/

    In this post, I will show you how to apply security at multiple layers of a web application hosted on AWS.

    Apply security at all layers is a design principle of the Security pillar of the AWS Well-Architected Framework. It encourages you to apply security at the network edge, virtual private cloud (VPC), load balancer, compute instance (or service), operating system, application, and code.

    Many popular web apps are designed with a single layer of security: the login page. Behind that login page is an in-built administration interface that is directly exposed to the internet. Admin interfaces for these apps typically have simple login mechanisms and often lack multi-factor authentication (MFA) support, which can make them an attractive target for threat actors.

    The in-built admin interface can also be problematic if you want to horizontally scale across multiple servers. The admin interface is available on every server that runs the app, so it creates a large attack surface. Because the admin interface updates the software on its own server, you must synchronize updates across a fleet of instances.

    Multi-layered security is about identifying (or creating) isolation boundaries around the parts of your architecture and minimizing what is permitted to cross each boundary. Adding more layers to your architecture gives you the opportunity to introduce additional controls at each layer, creating more boundaries where security controls can be enforced.

    In the example app scenario in this post, you have the opportunity to add many additional layers of security.

    Example of multi-layered security

    This post demonstrates how you can use the Run Web-Administered Apps on AWS sample project to help address these challenges, by implementing a horizontally-scalable architecture with multi-layered security. The project builds and configures many different AWS services, each designed to help provide security at different layers.

    By running this solution, you can produce a segmented architecture that separates the two functions of these apps into an unprivileged public-facing view and an admin view. This design limits access to the web app’s admin functions while creating a fleet of unprivileged instances to serve the app at scale.

    Figure 1 summarizes how the different services in this solution work to help provide security at the following layers:

    1. At the network edge
    2. Within the VPC
    3. At the load balancer
    4. On the compute instances
    5. Within the operating system
    Figure 1: Logical flow diagram to apply security at multiple layers

    Figure 1: Logical flow diagram to apply security at multiple layers

    Deep dive on a multi-layered architecture

    The following diagram shows the solution architecture deployed by Run Web-Administered Apps on AWS. The figure shows how the services deployed in this solution are deployed in different AWS Regions, and how requests flow from the application user through the different service layers.

    Figure 2: Multi-layered architecture

    Figure 2: Multi-layered architecture

    This post will dive deeper into each of the architecture’s layers to see how security is added at each layer. But before we talk about the technology, let’s consider how infrastructure is built and managed — by people.

    Perimeter 0 – Security at the people layer

    Security starts with the people in your team and your organization’s operational practices. How your “people layer” builds and manages your infrastructure contributes significantly to your security posture.

    A design principle of the Security pillar of the Well-Architected Framework is to automate security best practices. This helps in two ways: it reduces the effort required by people over time, and it helps prevent resources from being in inconsistent or misconfigured states. When people use manual processes to complete tasks, misconfigurations and missed steps are common.

    The simplest way to automate security while reducing human effort is to adopt services that AWS manages for you, such as Amazon Relational Database Service (Amazon RDS). With Amazon RDS, AWS is responsible for the operating system and database software patching, and provides tools to make it simple for you to back up and restore your data.

    You can automate and integrate key security functions by using managed AWS security services, such as Amazon GuardDuty, AWS Config, Amazon Inspector, and AWS Security Hub. These services provide network monitoring, configuration management, and detection of software vulnerabilities and unintended network exposure. As your cloud environments grow in scale and complexity, automated security monitoring is critical.

    Infrastructure as code (IaC) is a best practice that you can follow to automate the creation of infrastructure. By using IaC to define, configure, and deploy the AWS resources that you use, you reduce the likelihood of human error when building AWS infrastructure.

    Adopting IaC can help you improve your security posture because it applies the rigor of application code development to infrastructure provisioning. Storing your infrastructure definition in a source control system (such as AWS CodeCommit) creates an auditable artifact. With version control, you can track changes made to it over time as your architecture evolves.

    You can add automated testing to your IaC project to help ensure that your infrastructure is aligned with your organization’s security policies. If you ever need to recover from a disaster, you can redeploy the entire architecture from your IaC project.

    Another people-layer discipline is to apply the principle of least privilege. AWS Identity and Access Management (IAM) is a flexible and fine-grained permissions system that you can use to grant the smallest set of actions that your solution needs. You can use IAM to control access for both humans and machines, and we use it in this project to grant the compute instances the least privileges required.

    You can also adopt other IAM best practices such as using temporary credentials instead of long-lived ones (such as access keys), and regularly reviewing and removing unused users, roles, permissions, policies, and credentials.

    Perimeter 1 – network protections

    The internet is public and therefore untrusted, so you must proactively address the risks from threat actors and network-level attacks.

    To reduce the risk of distributed denial of service (DDoS) attacks, this solution uses AWS Shield for managed protection at the network edge. AWS Shield Standard is automatically enabled for all AWS customers at no additional cost and is designed to provide protection from common network and transport layer DDoS attacks. For higher levels of protection against attacks that target your applications, subscribe to AWS Shield Advanced.

    Amazon Route 53 resolves the hostnames that the solution uses and maps the hostnames as aliases to an Amazon CloudFront distribution. Route 53 is a robust and highly available globally distributed DNS service that inspects requests to protect against DNS-specific attack types, such as DNS amplification attacks.

    Perimeter 2 – request processing

    CloudFront also operates at the AWS network edge and caches, transforms, and forwards inbound requests to the relevant origin services across the low-latency AWS global network. The risk of DDoS attempts overwhelming your application servers is further reduced by caching web requests in CloudFront.

    The solution configures CloudFront to add a shared secret to the origin request within a custom header. A CloudFront function copies the originating user’s IP to another custom header. These headers get checked when the request arrives at the load balancer.

    AWS WAF, a web application firewall, blocks known bad traffic, including cross-site scripting (XSS) and SQL injection events that come into CloudFront. This project uses AWS Managed Rules, but you can add your own rules, as well. To restrict frontend access to permitted IP CIDR blocks, this project configures an IP restriction rule on the web application firewall.

    Perimeter 3 – the VPC

    After CloudFront and AWS WAF check the request, CloudFront forwards it to the compute services inside an Amazon Virtual Private Cloud (Amazon VPC). VPCs are logically isolated networks within your AWS account that you can use to control the network traffic that is allowed in and out. This project configures its VPC to use a private IPv4 CIDR block that cannot be directly routed to or from the internet, creating a network perimeter around your resources on AWS.

    The Amazon Elastic Compute Cloud (Amazon EC2) instances are hosted in private subnets within the VPC that have no inbound route from the internet. Using a NAT gateway, instances can make necessary outbound requests. This design hosts the database instances in isolated subnets that don’t have inbound or outbound internet access. Amazon RDS is a managed service, so AWS manages patching of the server and database software.

    The solution accesses AWS Secrets Manager by using an interface VPC endpoint. VPC endpoints use AWS PrivateLink to connect your VPC to AWS services as if they were in your VPC. In this way, resources in the VPC can communicate with Secrets Manager without traversing the internet.

    The project configures VPC Flow Logs as part of the VPC setup. VPC flow logs capture information about the IP traffic going to and from network interfaces in your VPC. GuardDuty analyzes these logs and uses threat intelligence data to identify unexpected, potentially unauthorized, and malicious activity within your AWS environment.

    Although using VPCs and subnets to segment parts of your application is a common strategy, there are other ways that you can achieve partitioning for application components:

    • You can use separate VPCs to restrict access to a database, and use VPC peering to route traffic between them.
    • You can use a multi-account strategy so that different security and compliance controls are applied in different accounts to create strong logical boundaries between parts of a system. You can route network requests between accounts by using services such as AWS Transit Gateway, and control them using AWS Network Firewall.

    There are always trade-offs between complexity, convenience, and security, so the right level of isolation between components depends on your requirements.

    Perimeter 4 – the load balancer

    After the request is sent to the VPC, an Application Load Balancer (ALB) processes it. The ALB distributes requests to the underlying EC2 instances. The ALB uses TLS version 1.2 to encrypt incoming connections with an AWS Certificate Manager (ACM) certificate.

    Public access to the load balancer isn’t allowed. A security group applied to the ALB only allows inbound traffic on port 443 from the CloudFront IP range. This is achieved by specifying the Region-specific AWS-managed CloudFront prefix list as the source in the security group rule.

    The ALB uses rules to decide whether to forward the request to the target instances or reject the traffic. As an additional layer of security, it uses the custom headers that the CloudFront distribution added to make sure that the request is from CloudFront. In another rule, the ALB uses the originating user’s IP to decide which target group of Amazon EC2 instances should handle the request. In this way, you can direct admin users to instances that are configured to allow admin tasks.

    If a request doesn’t match a valid rule, the ALB returns a 404 response to the user.

    Perimeter 5 – compute instance network security

    A security group creates an isolation boundary around the EC2 instances. The only traffic that reaches the instance is the traffic that the security group rules allow. In this solution, only the ALB is allowed to make inbound connections to the EC2 instances.

    A common practice is for customers to also open ports, or to set up and manage bastion hosts to provide remote access to their compute instances. The risk in this approach is that the ports could be left open to the whole internet, exposing the instances to vulnerabilities in the remote access protocol. With remote work on the rise, there is an increased risk for the creation of these overly permissive inbound rules.

    Using AWS Systems Manager Session Manager, you can remove the need for bastion hosts or open ports by creating secure temporary connections to your EC2 instances using the installed SSM agent. As with every software package that you install, you should check that the SSM agent aligns with your security and compliance requirements. To review the source code to the SSM agent, see amazon-ssm-agent GitHub repo.

    The compute layer of this solution consists of two separate Amazon EC2 Auto Scaling groups of EC2 instances. One group handles requests from administrators, while the other handles requests from unprivileged users. This creates another isolation boundary by keeping the functions separate while also helping to protect the system from a failure in one component causing the whole system to fail. Each Amazon EC2 Auto Scaling group spans multiple Availability Zones (AZs), providing resilience in the event of an outage in an AZ.

    By using managed database services, you can reduce the risk that database server instances haven’t been proactively patched for security updates. Managed infrastructure helps reduce the risk of security issues that result from the underlying operating system not receiving security patches in a timely manner and the risk of downtime from hardware failures.

    Perimeter 6 – compute instance operating system

    When instances are first launched, the operating system must be secure, and the instances must be updated as required when new security patches are released. We recommend that you create immutable servers that you build and harden by using a tool such as EC2 Image Builder. Instead of patching running instances in place, replace them when an updated Amazon Machine Image (AMI) is created. This approach works in our example scenario because the application code (which changes over time) is stored on Amazon Elastic File System (Amazon EFS), so when you replace the instances with a new AMI, you don’t need to update them with data that has changed after the initial deployment.

    Another way that the solution helps improve security on your instances at the operating system is to use EC2 instance profiles to allow them to assume IAM roles. IAM roles grant temporary credentials to applications running on EC2, instead of using hard-coded credentials stored on the instance. Access to other AWS resources is provided using these temporary credentials.

    The IAM roles have least privilege policies attached that grant permission to mount the EFS file system and access AWS Systems Manager. If a database secret exists in Secrets Manager, the IAM role is granted permission to access it.

    Perimeter 7 – at the file system

    Both Amazon EC2 Auto Scaling groups of EC2 instances share access to Amazon EFS, which hosts the files that the application uses. IAM authorization applies IAM file system policies to control the instance’s access to the file system. This creates another isolation boundary that helps prevent the non-admin instances from modifying the application’s files.

    The admin group’s instances have the file system mounted in read-write mode. This is necessary so that the application can update itself, install add-ons, upload content, or make configuration changes. On the unprivileged instances, the file system is mounted in read-only mode. This means that these instances can’t make changes to the application code or configuration files.

    The unprivileged instances have local file caching enabled. This caches files from the EFS file system on the local Amazon Elastic Block Store (Amazon EBS) volume to help improve scalability and performance.

    Perimeter 8 – web server configuration

    This solution applies different web server configurations to the instances running in each Amazon EC2 Auto Scaling group. This creates a further isolation boundary at the web server layer.

    The admin instances use the default configuration for the application that permits access to the admin interface. Non-admin, public-facing instances block admin routes, such as wp-login.php, and will return a 403 Forbidden response. This creates an additional layer of protection for those routes.

    Perimeter 9 – database security

    The database layer is within two additional isolation boundaries. The solution uses Amazon RDS, with database instances deployed in isolated subnets. Isolated subnets have no inbound or outbound internet access and can only be reached through other network interfaces within the VPC. The RDS security group further isolates the database instances by only allowing inbound traffic from the EC2 instances on the database server port.

    By using IAM authentication for the database access, you can add an additional layer of security by configuring the non-admin instances with less privileged database user credentials.

    Perimeter 10 – Security at the application code layer

    To apply security at the application code level, you should establish good practices around installing updates as they become available. Most applications have email lists that you can subscribe to that will notify you when updates become available.

    You should evaluate the quality of an application before you adopt it. The following are some metrics to consider:

    • Number of developers who are actively working on it
    • Frequency of updates to it
    • How quickly the developers respond with patches when bugs are reported

    Other steps that you can take

    Use AWS Verified Access to help secure application access for human users. With Verified Access, you can add another user authentication stage, to help ensure that only verified users can access an application’s administrative functions.

    Amazon GuardDuty is a threat detection service that continuously monitors your AWS accounts and workloads for malicious activity and delivers detailed security findings for visibility and remediation. It can detect communication with known malicious domains and IP addresses and identify anomalous behavior. GuardDuty Malware Protection helps you detect the potential presence of malware by scanning the EBS volumes that are attached to your EC2 instances.

    Amazon Inspector is an automated vulnerability management service that automatically discovers the Amazon EC2 instances that are running and scans them for software vulnerabilities and unintended network exposure. To help ensure that your web server instances are updated when security patches are available, use AWS Systems Manager Patch Manager.

    Deploy the sample project

    We wrote the Run Web-Administered Apps on AWS project by using the AWS Cloud Development Kit (AWS CDK). With the AWS CDK, you can use the expressive power of familiar programming languages to define your application resources and accelerate development. The AWS CDK has support for multiple languages, including TypeScript, Python, .NET, Java, and Go.

    This project uses Python. To deploy it, you need to have a working version of Python 3 on your computer. For instructions on how to install the AWS CDK, see Get Started with AWS CDK.

    Configure the project

    To enable this project to deploy multiple different web projects, you must do the configuration in the parameters.properties file. Two variables identify the configuration blocks: app (which identifies the web application to deploy) and env (which identifies whether the deployment is to a dev or test environment, or to production).

    When you deploy the stacks, you specify the app and env variables as CDK context variables so that you can select between different configurations at deploy time. If you don’t specify a context, a [default] stanza in the parameters.properties file specifies the default app name and environment that will be deployed.

    To name other stanzas, combine valid app and env values by using the format <app>-<env>. For each stanza, you can specify its own Regions, accounts, instance types, instance counts, hostnames, and more. For example, if you want to support three different WordPress deployments, you might specify the app name as wp, and for env, you might want devtest, and prod, giving you three stanzas: wp-devwp-test, and wp-prod.

    The project includes sample configuration items that are annotated with comments that explain their function.

    Use CDK bootstrapping

    Before you can use the AWS CDK to deploy stacks into your account, you need to use CDK bootstrapping to provision resources in each AWS environment (account and Region combination) that you plan to use. For this project, you need to bootstrap both the US East (N. Virginia) Region (us-east-1)  and the home Region in which you plan to host your application.

    Create a hosted zone in the target account

    You need to have a hosted zone in Route 53 to allow the creation of DNS records and certificates. You must manually create the hosted zone by using the AWS Management Console. You can delegate a domain that you control to Route 53 and use it with this project. You can also register a domain through Route 53 if you don’t currently have one.

    Run the project

    Clone the project to your local machine and navigate to the project root. To create the Python virtual environment (venv) and install the dependencies, follow the steps in the Generic CDK instructions.

    To create and configure the parameters.properties file

    Copy the parameters-template.properties file (in the root folder of the project) to a file called parameters.properties and save it in the root folder. Open it with a text editor and then do the following:

    If you want to restrict public access to your site, change 192.0.2.0/24 to the IP range that you want to allow. By providing a comma-separated list of allowedIps, you can add multiple allowed CIDR blocks.

    If you don’t want to restrict public access, set allowedIps=* instead.

    If you have forked this project into your own private repository, you can commit the parameters.properties file to your repo. To do that, comment out the parameters.properties  line in the .gitignore file.

    To install the custom resource helper

    The solution uses an AWS CloudFormation custom resource for cross-Region configuration management. To install the needed Python package, run the following command in the custom_resource directory:

    cd custom_resource
    pip install crhelper -t .

    To learn more about CloudFormation custom resource creation, see AWS CloudFormation custom resource creation with Python, AWS Lambda, and crhelper.

    To configure the database layer

    Before you deploy the stacks, decide whether you want to include a data layer as part of the deployment. The dbConfig parameter determines what will happen, as follows:

    • If dbConfig is left empty — no database will be created and no database credentials will be available in your compute stacks
    • If dbConfig is set to instance — you will get a new Amazon RDS instance
    • If dbConfig is set to cluster — you will get an Amazon Aurora cluster
    • If dbConfig is set to none — if you previously created a database in this stack, the database will be deleted

    If you specify either instance or cluster, you should also configure the following database parameters to match your requirements:

    • dbEngine — set the database engine to either mysql or postgres
    • dbSnapshot — specify the named snapshot for your database
    • dbSecret — if you are using an existing database, specify the Amazon Resource Name (ARN) of the secret where the database credentials and DNS endpoint are located
    • dbMajorVersion — set the major version of the engine that you have chosen; leave blank to get the default version
    • dbFullVersion — set the minor version of the engine that you have chosen; leave blank to get the default version
    • dbInstanceType — set the instance type that you want (note that these vary by service); don’t prefix with db. because the CDK will automatically prepend it
    • dbClusterSize — if you request a cluster, set this parameter to determine how many Amazon Aurora replicas are created

    You can choose between mysql or postgres for the database engine. Other settings that you can choose are determined by that choice.

    You will need to use an Amazon Machine Image (AMI) that has the CLI preinstalled, such as Amazon Linux 2, or install the AWS Command Line Interface (AWS CLI) yourself with a user data command. If instead of creating a new, empty database, you want to create one from a snapshot, supply the snapshot name by using the dbSnapshot parameter.

    To create the database secret

    AWS automatically creates and stores the RDS instance or Aurora cluster credentials in a Secrets Manager secret when you create a new instance or cluster. You make these credentials available to the compute stack through the db_secret_command variable, which contains a single-line bash command that returns the JSON from the AWS CLI command aws secretsmanager get-secret-value. You can interpolate this variable into your user data commands as follows:

    SECRET=$({db_secret_command})
    USERNAME=`echo $SECRET | jq -r '.username'`
    PASSWORD=`echo $SECRET | jq -r '.password'`
    DBNAME=`echo $SECRET | jq -r '.dbname'`
    HOST=`echo $SECRET | jq -r '.host'`

    If you create a database from a snapshot, make sure that your Secrets Manager secret and Amazon RDS snapshot are in the target Region. If you supply the secret for an existing database, make sure that the secret contains at least the following four key-value pairs (replace the <placeholder values> with your values):

    {
        "password":"<your-password>",
        "dbname":"<your-database-name>",
        "host":"<your-hostname>",
        "username":"<your-username>"
    }

    The name for the secret must match the app value followed by the env value (both in title case), followed by DatabaseSecret, so for app=wp and env=dev, your secret name should be WpDevDatabaseSecret.

    To deploy the stacks

    The following commands deploy the stacks defined in the CDK app. To deploy them individually, use the specific stack names (these will vary according to the info that you supplied previously), as shown in the following.

    cdk deploy wp-dev-network-stack -c app=wp -c env=dev
    cdk deploy wp-dev-database-stack -c app=wp -c env=dev
    cdk deploy wp-dev-compute-stack -c app=wp -c env=dev
    cdk deploy wp-dev-cdn-stack -c app=wp -c env=dev

    To create a database stack, deploy the network and database stacks first.

    cdk deploy wp-dev-network-stack -c app=wp -c env=dev
    cdk deploy wp-dev-database-stack -c app=wp -c env=dev

    You can then initiate the deployment of the compute stack.

    cdk deploy wp-dev-compute-stack -c app=wp -c env=dev

    After the compute stack deploys, you can deploy the stack that creates the CloudFront distribution.

    cdk deploy wp-dev-cdn-stack -c env=dev

    This deploys the CloudFront infrastructure to the US East (N. Virginia) Region (us-east-1). CloudFront is a global AWS service, which means that you must create it in this Region. The other stacks are deployed to the Region that you specified in your configuration stanza.

    To test the results

    If your stacks deploy successfully, your site appears at one of the following URLs:

    • subdomain.hostedZone (if you specified a value for the subdomain) — for example, www.example.com
    • appName-env.hostedZone (if you didn’t specify a value for the subdomain) — for example, wp-dev.example.com.

    If you connect through the IP address that you configured in the adminIps configuration, you should be connected to the admin instance for your site. Because the admin instance can modify the file system, you should use it to do your administrative tasks.

    Users who connect to your site from an IP that isn’t in your allowedIps list will be connected to your fleet instances and won’t be able to alter the file system (for example, they won’t be able to install plugins or upload media).

    If you need to redeploy the same app-env combination, manually remove the parameter store items and the replicated secret that you created in us-east-1. You should also delete the cdk.context.json file because it caches values that you will be replacing.

    One project, multiple configurations

    You can modify the configuration file in this project to deploy different applications to different environments using the same project. Each app can have different configurations for dev, test, or production environments.

    Using this mechanism, you can deploy sites for test and production into different accounts or even different Regions. The solution uses CDK context variables as command-line switches to select different configuration stanzas from the configuration file.

    CDK projects allow for multiple deployments to coexist in one account by using unique names for the deployed stacks, based on their configuration.

    Check the configuration file into your source control repo so that you track changes made to it over time.

    Got a different web app that you want to deploy? Create a new configuration by copying and pasting one of the examples and then modify the build commands as needed for your use case.

    Conclusion

    In this post, you learned how to build an architecture on AWS that implements multi-layered security. You can use different AWS services to provide protections to your application at different stages of the request lifecycle.

    You can learn more about the services used in this sample project by building it in your own account. It’s a great way to explore how the different services work and the full features that are available. By understanding how these AWS services work, you will be ready to use them to add security, at multiple layers, in your own architectures.

     
    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
    Want more AWS Security news? Follow us on Twitter.

    Guy Morton

    Guy Morton

    Guy is a Senior Solutions Architect at AWS. He enjoys bringing his decades of experience as a full stack developer, architect, and people manager to helping customers build and scale their applications securely in the AWS Cloud. Guy has a passion for automation in all its forms, and is also an occasional songwriter and musician who performs under the pseudonym Whtsqr.

    Mutual authentication for Application Load Balancer reliably verifies certificate-based client identities

    Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/mutual-authentication-for-application-load-balancer-to-reliably-verify-certificate-based-client-identities/

    Today, we are announcing support for mutually authenticating clients that present X509 certificates to Application Load Balancer. With this new feature, you can now offload client authentication to the load balancer, ensuring only trusted clients communicate with their backend applications. This new capability is built on S2N, AWS’s open source Transport Layer Security (TLS) implementation that provides strong encryption and protections against zero-day vulnerabilities, which developers can trust.

    Mutual authentication (mTLS) is commonly used for business-to-business (B2B) applications such as online banking, automobile, or gaming devices to authenticate devices using digital certificates. Companies typically use it with a private certificate authority (CA) to authenticate their clients before granting access to data and services.

    Customers have implemented mutual authentication using self-created or third-party solutions that require additional time and management overhead. These customers spend their engineering resources to build the functionality into their backend, update their code to keep up with the latest security patches, and invest heavily in infrastructure to create and rotate certificates.

    With mutual authentication on Application Load Balancer, you have a fully managed, scalable, and cost-effective solution that enables you to use your developer resources to focus on other critical projects. Your ALB will authenticate clients with revocation checks and pass client certificate information to the target, which can be used for authorization by applications.

    Getting started with mutual authentication on ALB
    To enable mutual authentication on ALB, choose Create Application Load Balancer by the ALB wizard on Amazon EC2 console. When you select HTTPS in the Listeners and routing section, you can see more settings such as security policy, default server certificate, and a new client certificate handling option to support mutual authentication.

    With Mutual authentication (mTLS) enabled, you can configure how listeners handle requests that present client certificates. This includes how your Application Load Balancer authenticates certificates and the amount of certificate metadata that is sent to your backend targets.

    Mutual authentication has two options. The Passthrough option sends all the client certificate chains received from the client to your backend application using HTTP headers. The mTLS-enabled Application Load Balancer gets the client certificate in the handshake, establishes a TLS connection, and then sends whatever it gets in HTTPS headers to the target application. The application will need to verify the client certificate chain to authenticate the client.

    With the Verify with trust store option, Application Load Balancer and client verify each other’s identity and establish a TLS connection to encrypt communication between them. We introduce a new trust store feature, and you can upload any CA bundle with roots and/or intermediate certificates generated by AWS Private Certificate Authority or any other third party CA as the source of trust to validate your client certificates.

    It requires selecting an existing trust store or creating a new one. Trust stores contain your CAs, trusted certificates, and, optionally, certificate revocation lists (CRLs). The load balancer uses a trust store to perform mutual authentication with clients.

    To use this option and create a new trust store, choose Trust Stores in the left menu of the Amazon EC2 console and choose Create trust store.

    You can choose a CA certificate bundle in PEM format and, optionally, CRLs from your Amazon Simple Storage Service (Amazon S3) bucket. A CA certificate bundle is a group of CA certificates (root or intermediate) used by a trust store. CRLs can be used when a CA revokes client certificates that have been compromised, and you need to reject those revoked certificates. You can replace a CA bundle, and add or remove CRLs from the trust store after creation.

    You can use the AWS Command Line Interface (AWS CLI) with new APIs such as create-trust-store to upload CA information, configure the mutual-authentication-mode on the Application Load Balancer listener, and send user certificate information to targets.

    $ aws elbv2 create-trust-store --name my-tls-name \
        --ca-certificates-bundle-s3-bucket channy-certs \
        --ca-certificates-bundle-s3-key Certificates.pem \
        --ca-certificates-bundle-s3-object-version <version>
    >> arn:aws:elasticloadbalancing:root:file1
    $ aws elbv2 create-listener --load balancer-arn <value> \
        --protocol HTTPS \
        --port 443 \
        --mutual-authentication Mode=verify,
          TrustStoreArn=<arn:aws:elasticloadbalancing:root:file1>

    If you already have your own private CA, such as AWS Private CA, third-party CA, or self-signed CA, you can upload their CA bundle or CRLs to the Application Load Balancer trust store to enable mutual authentication.

    To test the mutual authentication on Application Load Balancer, follow the step-by-step instructions to make a self-signed CA bundle and client certificate using OpenSSL, upload them to the Amazon S3 bucket, and use them with an ELB trust store.

    You can use curl with the --key and --cert parameters to send the client certificate as part of the request:

    $ curl --key my_client.key --cert my_client.pem https://api.yourdomain.com

    Mutual authentication can fail if a client presents an invalid or expired certificate, fails to present a certificate, cannot find a trust chain, or if any links in the trust chain have expired, or the certificate is on the revocation list.

    Application Load Balancer will close the connections whenever it fails to authenticate a client and will record new connection logs that capture detailed information about requests sent to your load balancer. Each log contains information such as the client’s IP address, handshake latency, TLS cipher used, and client certificate details. You can use these connection logs to analyze request patterns and troubleshoot issues.

    To learn more, see Mutual authentication on Application Load Balancer in the AWS documentation.

    Now available
    Mutual authentication on Application Load Balancer is now available in all commercial AWS Regions where Application Load Balancer is available, except China. With no upfront costs or commitments required, you only pay for what you use. To learn more, see the Elastic Load Balancing pricing page.

    Give it a try now and send feedback to AWS re:Post for Amazon EC2 or through your usual AWS Support contacts.

    Learn more:
    Application Load Balancer product page

    Channy

    How Sonar built a unified API on AWS

    Post Syndicated from Patrick Madec original https://aws.amazon.com/blogs/architecture/how-sonar-built-a-unified-api-on-aws/

    SonarCloud, a software-as-a-service (SaaS) product developed by Sonar, seamlessly integrates into developers’ CI/CD workflows to increase code quality and identify vulnerabilities. Over the last few months, Sonar’s cloud engineers have worked on modernizing SonarCloud to increase the lead time to production.

    Following Domain Driven Design principles, Sonar split the application into multiple business domains, each owned by independent teams. They also built a unified API to expose these domains publicly.

    This blog post will explore Sonar’s design for SonarCloud’s unified API, utilizing Elastic Load Balancing, AWS PrivateLink, and Amazon API Gateway. Then, we’ll uncover the benefits aligned with the AWS Well-Architected Framework including enhanced security and minimal operational overhead.

    This solution isn’t exclusive to Sonar; it’s a blueprint for organizations modernizing their applications towards domain-driven design or microservices with public service exposure.

    Introduction

    SonarCloud’s core was initially built as a monolithic application on AWS, managed by a single team. Over time, it gained widespread adoption among thousands of organizations, leading to the introduction of new features and contributions from multiple teams.

    In response to this growth, Sonar recognized the need to modernize its architecture. The decision was made to transition to domain-driven design, aligning with the team’s structure. New functionalities are now developed within independent domains, managed by dedicated teams, while existing components are gradually refactored using the strangler pattern.

    This transformation resulted in SonarCloud being composed of multiple domains, and securely exposing them to customers became a key challenge. To address this, Sonar’s engineers built a unified API, a solution we’ll explore in the following section.

    Solution overview

    Figure 1 illustrates the architecture of the unified API, the gateway through which end-users access SonarCloud services. It is built on an Application Load Balancer and Amazon API Gateway private APIs.

    Unified API architecture

    Figure 1. Unified API architecture

    The VPC endpoint for API Gateway spans three Availability Zones (AZs), providing an Elastic Network Interface (ENI) in each private subnet. Meanwhile, the ALB is configured with an HTTPS listener, linked to a target group containing the IP addresses of the ENIs.

    To streamline access, we’ve established an API Gateway custom domain at api.example.com. Within this domain, we’ve created API mappings for each domain. This setup allows for seamless routing, with paths like /domain1 leading directly to the corresponding domain1 private API of the API Gateway service.

    Here is how it works:

    1. The user makes a request to api.example.com/domain1, which is routed to the ALB using Amazon Route53 for DNS resolution.
    2. The ALB terminates the connection, decrypts the request and sends it to one of the VPC endpoint ENIs. At this point, the domain name and the path of the request respectively match our custom domain name, api.example.com, and our API mapping for /domain1.
    3. Based on the custom domain name and API mapping, the API Gateway service routes the request to the domain1 private API.

    In this solution, we leverage the two following functionalities of the Amazon API Gateway:

    • Private REST APIs in Amazon API Gateway can only be accessed from your virtual private cloud by using an interface VPC endpoint. This is an ENI that you create in your VPC.
    • API Gateway custom domains allow you to set up your API’s hostname. The default base URL for an API is:
      https://api-id.execute-api.region.amazonaws.com/stage

      With custom domains you can define a more intuitive URL, such as:
      https://api.example.com/domain1This is not supported for private REST APIs by default so we are using a workaround documented in https://github.com/aws-samples/.

    Conclusion

    In this post, we described the architecture of a unified API built by Sonar to securely expose multiple domains through a single API endpoint. To conclude, let’s review how this solution is aligned with the best practices of the AWS Well-Architected Framework.

    Security

    The unified API approach improves the security of the application by reducing the attack surface as opposed to having a public API per domain. AWS Web Application Firewall (WAF) used on the ALB protects the application from common web exploits. AWS Shield, enabled by default on Amazon CloudFront, provides Network/Transport layer protection against DDoS attacks.

    Operational Excellence

    The design allows each team to independently deploy application and infrastructure changes behind a dedicated private API Gateway. This leads to a minimal operational overhead for the platform team and was a requirement. In addition, the architecture is based on managed services, which scale automatically as SonarCloud usage evolves.

    Reliability

    The solution is built using AWS services providing high-availability by default across Availability Zones (AZs) in the AWS Region. Requests throttling can be configured on each private API Gateway to protect the underlying resources from being overwhelmed.

    Performance

    Amazon CloudFront increases the performance of the API, especially for users located far from the deployment AWS Region. The traffic flows through the AWS network backbone which offers superior performance for accessing the ALB.

    Cost

    The ALB is used as the single entry-point and brings an extra cost as opposed to exposing multiple public API Gateways. This is a trade-off for enhanced security and customer experience.

    Sustainability

    By using serverless managed services, Sonar is able to match the provisioned infrastructure with the customer demand. This avoids overprovisioning resources and reduces the environmental impact of the solution.

    Further reading

    Multiple Load Balance Support in AWS CodeDeploy

    Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/multiple-load-balance-support-in-codedeploy/

    AWS CodeDeploy is a fully managed deployment service that automates software deployments to various compute services, such as Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (ECS), AWS Lambda, and on-premises servers. AWS CodeDeploy recently announced support for deploying to applications that use multiple AWS Elastic Load Balancers (ELB). CodeDeploy now supports multiple Classic Load Balancers (CLB), and multiple target groups associated with Application Load Balancers (ALB) or Network Load Balancer (NLB) when using CodeDeploy with Amazon EC2. In this blog post, I will show you how to deploy an application served by multiple load balancers.

    Background

    AWS CodeDeploy simplifies deploying application updates across Amazon EC2 instances registered with Elastic Load Balancers. The integration provides an automated, scalable way to deploy updates without affecting application availability.

    To use CodeDeploy with load balancers, you install the CodeDeploy agent on Amazon EC2 instances that have been registered as targets of a Classic, Application, or Network Load Balancer. When creating a CodeDeploy deployment group, you specify the load balancer and target groups you want to deploy updates to.

    During deployment, CodeDeploy safely shifts traffic by deregistering instances from the load balancer, deploying the new application revision, and then re-registering the instances to route traffic back. This approach ensures application capacity and availability are maintained throughout the deployment process. CodeDeploy coordinates the traffic shift across groups of instances, so that the deployment rolls out in a controlled fashion.

    CodeDeploy offers two deployment approaches to choose from based on your needs: in-place deployments and blue/green deployments. With in-place deployments, traffic is shifted to the new application revision on the same set of instances. This allows performing rapid, incremental updates. Blue/green deployments involve shifting traffic to a separate fleet of instances running the new revision. This approach enables easy rollback if needed. CodeDeploy makes it easy to automate either deployment strategy across your infrastructure.

    Architectures with Multiple Load Balancers

    CodeDeploy’s expanded integration with Elastic Load Balancing unlocks new deployment flexibility. Users can now register multiple Classic Load Balancers and multiple target groups associated with Application or Network Load Balancers. This allows you to deploy updates across complex applications that leverage multiple target groups. For example, many customers run applications that serve both an internal audience and external audience. Often, these two audiences require different authentication and security requirements. It is common to provide access to the internal and external audiences through different load balancers, as shown in the following image.

    Architecture showing two load balancers, one external facing and one internal facing

    In the past, CodeDeploy only supported one load balancer per application. Customers running internal and external application tiers would have to duplicate environments, using separate EC2 instances and Amazon EC2 Auto Scaling groups for each audience. This resulted in overprovisioning and added overhead to manage duplicate resources.

    With multiple load balancer support, CodeDeploy removes the need to duplicate environments. Users can now deploy updates to a single environment, and CodeDeploy will manage the deployment across both the internal and external load balancers. You simply select all the target groups used by your application, as shown in the following image.

    CodeDeploy configuration showing two load balancers selected

    This consolidated approach reduces infrastructure costs and operational complexity when automating deployments. CodeDeploy orchestrates the in-place or blue/green deployment across multiple load balanced target groups.

    Migrating from a Classic Load Balancer

    Many customers are migrating from Classic Load Balancers (CLB) to Application Load Balancers (ALB) or Network Load Balancers (NLB). ALB and NLB offer a more modern and advanced feature set than CLB, including integrated path-based and host-based routing, and native IPv6 support. They also deliver improved load balancing performance with higher throughput and lower latency. Other benefits include native integrations with AWS WAF, Shield, and Global Accelerator along with potential cost savings from requiring fewer load balancers. Overall, migrating to ALB or NLB provides an opportunity to gain advanced capabilities, better performance, tighter service integration, and reduced costs.

    CodeDeploy’s new multi-target group capabilities streamline migrating from Classic Load Balancers (CLB) to Application or Network Load Balancers (ALB or NLB). Users can now deploy applications utilizing both legacy CLB and modern ALB or NLB in parallel during the transition. This enables gracefully testing integration with the new load balancers before fully cutting over. Once you verify that users have stopped using the CLB endpoint, you can delete the CLB.

    During the transition period, CodeDeploy orchestrates deployments across the CLB and target groups tied to the ALB or NLB within a single automation. Users simply select the CLB and target groups of the new load balancer in the deployment group as shown in the following image.

    CodeDeploy configuration showing a both a classic load balancer and target group selected

    This consolidated approach lets CodeDeploy coordinate a staged rollout across CLB and ALB/NLB. With simplified management of multiple load balancers, CodeDeploy eases the critical process of modernizing infrastructure while maintaining application availability.

    Conclusion

    CodeDeploy’s expanded integration with Elastic Load Balancing allows more flexible application deployments. Support for multiple Classic Load Balancers and multiple target groups associated with Application or Network Load Balancers enables you to seamlessly update complex architectures on AWS. Whether you are consolidating disparate environments or migrating from Classic Load Balancers, CodeDeploy simplifies managing deployments across multiple load balanced tiers. To learn more, see Integrating CodeDeploy with Elastic Load Balancing in the AWS CodeDeploy Developer Guide or visit the CodeDeploy product page.

    AWS Week in Review – March 27, 2023

    Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-march-27-2023/

    This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

    In Finland, where I live, spring has arrived. The snow has melted, and the trees have grown their first buds. But I don’t get my hopes high, as usually around Easter we have what is called takatalvi. Takatalvi is a Finnish world that means that the winter returns unexpectedly in the spring.

    Last Week’s Launches
    Here are some launches that got my attention during the previous week.

    AWS SAM CLI – Now the sam sync command will compare your local Serverless Application Model (AWS SAM) template with your deployed AWS CloudFormation template and skip the deployment if there are no changes. For more information, check the latest version of the AWS SAM CLI.

    IAM – AWS Identity and Access Management (IAM) has launched two new global condition context keys. With these new condition keys, you can write service control policies (SCPs) or IAM policies that restrict the VPCs and private IP addresses from which your Amazon Elastic Compute Cloud (Amazon EC2) instance credentials can be used, without hard-coding VPC IDs or IP addresses in the policy. To learn more about this launch and how to get started, see How to use policies to restrict where EC2 instance credentials can be used from.

    Amazon SNS – Amazon Simple Notification Service (Amazon SNS) now supports setting context-type request headers for HTTP/S notifications, such as application/json, application/xml, or text/plain. With this new feature, applications can receive their notifications in a more predictable format.

    AWS Batch – AWS Batch now allows you to configure ephemeral storage up to 200GiB on AWS Fargate type jobs. With this launch, you no longer need to limit the size of your data sets or the size of the Docker images to run machine learning inference.

    Application Load Balancer – Application Load Balancer (ALB) now supports Transport Layer Security (TLS) protocol version 1.3, enabling you to optimize the performance of your application while keeping it secure. TLS 1.3 on ALB works by offloading encryption and decryption of TLS traffic from your application server to the load balancer.

    Amazon IVS – Amazon Interactive Video Service (IVS) now supports combining videos from multiple hosts into the source of a live stream. For a demo, refer to Add multiple hosts to live streams with Amazon IVS.

    For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

    Other AWS News
    Some other updates and news that you may have missed:

    I read the post Implementing an event-driven serverless story generation application with ChatGPT and DALL-E a few days ago, and since then I have been reading my child a lot of  AI-generated stories. In this post, David Boyne, explains step by step how you can create an event-driven serverless story generation application. This application produces a brand-new story every day at bedtime with images, which can be played in audio format.

    Podcast Charlas Técnicas de AWS – If you understand Spanish, this podcast is for you. Podcast Charlas Técnicas is one of the official AWS podcasts in Spanish, and every other week there is a new episode. The podcast is meant for builders, and it shares stories about how customers have implemented and learned AWS services, how to architect applications, and how to use new services. You can listen to all the episodes directly from your favorite podcast app or at AWS Podcasts en español.

    AWS open-source news and updates – The open source newsletter is curated by my colleague Ricardo Sueiras to bring you the latest open-source projects, posts, events, and more.

    Upcoming AWS Events
    Check your calendars and sign up for the AWS Summit closest to your city. AWS Summits are free events that bring the local community together, where you can learn about different AWS services.

    Here are the ones coming up in the next months:

    That’s all for this week. Check back next Monday for another Week in Review!

    — Marcia

    Choosing an AWS container service to run your modern application

    Post Syndicated from Lewis Tang original https://aws.amazon.com/blogs/architecture/choosing-an-aws-container-service-to-run-your-modern-application/

    Businesses want to innovate quickly and deliver value even faster. To achieve these goals, the platform needs to enable teams to focus on delivering applications that are reliable, secure, highly available, cost-efficient, and scalable to required sizes.

    Consider including containers on AWS in your platform, whether you are trying containers for the first time, spinning out parts of an on-premises solution to microservices in the cloud, or are new to the cloud. Containers can help you achieving a range of business benefits, including increased scalability, agility, flexibility, and cost efficiency.

    In this post, we discuss three sets of builder expectations and how AWS container services can help to meet with your application delivery requirements and choose the appropriate container platform service on AWS.

    Decrease container platform operations management overhead

    If managing a platform is not your business’s strategic focus (for example, if most of your engineers are code developers), it can be preferable to only manage application development.

    Amazon Lightsail containers offer a simple way for developers to deploy their containers to the cloud. With a Docker image you provide for your containers, AWS automatically deploys containerized workloads for you.

    Lightsail assigns an HTTPS endpoint that is ready to serve your web application running in the cloud container. It automatically sets up a load-balanced Transport Layer Security (TLS) endpoint and takes care of the TLS certificate. This service replaces unresponsive containers for you automatically; by assigning a Domain Name System to your endpoint, Lightsail maintains the old version until the new version is healthy and ready to go live (Figure 1).

    Amazon Lightsail containers

    Figure 1. Amazon Lightsail containers

    Another simple way to build and run your containerized web application in AWS is using AWS App Runner, which provides a fully managed container-native service.

    Without orchestrators to configure, build pipelines to set up, or load balancers to optimize, you can bring existing containers or use the integrated container build service to go directly from the code repository to deployed application.

    The build service can connect to a GitHub repository, providing a Git push workflow that deploys changes automatically. App Runner orchestration workflow take cares of the build, deployment, and configuration tasks, such as host, runtime patching, monitoring load balancing, and auto scaling (Figure 2). Explore AWS App Runner documentation and workshop for more details about the service.

    AWS App Runner

    Figure 2. AWS App Runner

    When designing an application, you often start with a whiteboard or mental model that has representations of each service and lines for how they interact with each other. When considering an application’s platform architecture, the cloud components are not limited to virtual private cloud (VPC) subnets, load balancers, deployment pipelines, and durable storage for your application’s stateful data. Bringing all underlying cloud components together and making sure the design is well architected can be challenging.

    AWS Copilot can provide guided best practices when deploying a microservice architecture that includes multiple services deployed as containers. You can use Copliot to handle cloud component details for you. By providing a container image, Copilot works with App Runner or Amazon Elastic Container Service (Amazon ECS) to provision cloud components, like VPC and having Copilot handle high-availability deployment, load balancer creation, and configuration.

    To automate application deployment and new version release, Copilot can create a deployment pipeline so that the latest version of your application is automatically deployed every time you push a new commit to your code repository (as demonstrated in Figure 3).

    AWS Copilot pipeline

    Figure 3. AWS Copilot pipeline

    Full-control application deployment with container orchestration

    As business grows, your application portfolio grows. Some applications may require the selection of Microsoft Windows containers or deep customizations on container-resource scheduling, monitoring, and logging. To accommodate this, you need the flexibility of configuring the required underlying container services while still using the efficient container orchestrator to automate the common processes to achieve operation efficiency. This is where Amazon ECS and Amazon Elastic Kubernetes Service (Amazon EKS) can help.

    Using Amazon ECS

    As demonstrated in Figure 4, Amazon ECS is a highly scalable, high-performance container management service that supports containers and allows you to easily run applications on a managed cluster of Amazon Elastic Compute Cloud instances with Amazon Fargate (a serverless compute engine for containers). With this, you can launch and stop containerized applications and query the complete state of your cluster. You have the ability to access and configure many familiar features, like security groups and Elastic Load Balancing (ELB), by sending simple API calls.

    Amazon ECS can be used to schedule container placement across your cluster based on resource needs and availability requirements. You can also integrate your own scheduler or third-party schedulers to meet business- or application-specific requirements.

    Amazon ECS using AWS Fargate

    Figure 4. Amazon ECS using AWS Fargate

    Using Amazon EKS

    Amazon EKS is a managed service that can be used to run Kubernetes on AWS, without installing, operating, and maintaining your own Kubernetes control plane or nodes. For many developers who have experience using Kubernetes, running Amazon EKS for application container workload is a preferred option because Amazon EKS provides the flexibility of Kubernetes with the scalability, security and resiliency of being an AWS managed service.

    Amazon EKS runs and automatically scales the Kubernetes control plane across multiple AWS availability zones to ensure high availability, as in Figure 5. The control plane instances are automatically scaled based on load. Amazon EKS detects and replaces unhealthy control plane instances and provides automated version updates and patching. Amazon EKS enables developers to run up-to-date versions of the open-source Kubernetes software, the existing or new third-party plugins, and tooling. This means you can more easily migrate any standard Kubernetes application to Amazon EKS without code modification.

    Scalability and security are essential to your business-critical workloads. Amazon EKS is integrated with many AWS services, including Amazon Elastic Container Registry for container images, ELB for load distribution, IAM for authentication, and Amazon Virtual Private Cloud for isolation.

    Amazon EKS scales Kubernetes across multiple availability zones

    Figure 5. Amazon EKS scales Kubernetes across multiple availability zones

    Conclusion

    To innovate and respond to changes faster, businesses need to build modern applications quickly and manage them efficiently. AWS provides container services to run your most sensitive, secure, and business-critical workloads reliably and to-scale.

    With little-to-no prior container experience, developers can use Lightsail containers to run web application container workloads with easy-to-use interface. App Runner simplifies application deployment and management down into one particular service for running web applications. With Copilot, you can get step-by-step best practice guidance when you need to deploy microservice architecture with multiple services deployed as containers. Amazon ECS and Amazon EKS give the flexibility of configuring container workloads while maintaining the application deployment and operational efficiency.

    Further reading

    Top 2021 AWS service launches security professionals should review – Part 2

    Post Syndicated from Marta Taggart original https://aws.amazon.com/blogs/security/top-2021-aws-service-launches-security-professionals-should-review-part-2/

    In Part 1 of this two-part series, we shared an overview of some of the most important 2021 Amazon Web Services (AWS) Security service and feature launches. In this follow-up, we’ll dive deep into additional launches that are important for security professionals to be aware of and understand across all AWS services. There have already been plenty in the first half of 2022, so we’ll highlight those soon, as well.

    AWS Identity

    You can use AWS Identity Services to build Zero Trust architectures, help secure your environments with a robust data perimeter, and work toward the security best practice of granting least privilege. In 2021, AWS expanded the identity source options, AWS Region availability, and support for AWS services. There is also added visibility and power in the permission management system. New features offer new integrations, additional policy checks, and secure resource sharing across AWS accounts.

    AWS Single Sign-On

    For identity management, AWS Single Sign-On (AWS SSO) is where you create, or connect, your workforce identities in AWS once and manage access centrally across your AWS accounts in AWS Organizations. In 2021, AWS SSO announced new integrations for JumpCloud and CyberArk users. This adds to the list of providers that you can use to connect your users and groups, which also includes Microsoft Active Directory Domain Services, Okta Universal Directory, Azure AD, OneLogin, and Ping Identity.

    AWS SSO expanded its availability to new Regions: AWS GovCloud (US), Europe (Paris), and South America (São Paulo) Regions. Another very cool AWS SSO development is its integration with AWS Systems Manager Fleet Manager. This integration enables you to log in interactively to your Windows servers running on Amazon Elastic Compute Cloud (Amazon EC2) while using your existing corporate identities—try it, it’s fantastic!

    AWS Identity and Access Management

    For access management, there have been a range of feature launches with AWS Identity and Access Management (IAM) that have added up to more power and visibility in the permissions management system. Here are some key examples.

    IAM made it simpler to relate a user’s IAM role activity to their corporate identity. By setting the new source identity attribute, which persists through role assumption chains and gets logged in AWS CloudTrail, you can find out who is responsible for actions that IAM roles performed.

    IAM added support for policy conditions, to help manage permissions for AWS services that access your resources. This important feature launch of service principal conditions helps you to distinguish between API calls being made on your behalf by a service principal, and those being made by a principal inside your account. You can choose to allow or deny the calls depending on your needs. As a security professional, you might find this especially useful in conjunction with the aws:CalledVia condition key, which allows you to scope permissions down to specify that this account principal can only call this API if they are calling it using a particular AWS service that’s acting on their behalf. For example, your account principal can’t generally access a particular Amazon Simple Storage Service (Amazon S3) bucket, but if they are accessing it by using Amazon Athena, they can do so. These conditions can also be used in service control policies (SCPs) to give account principals broader scope across an account, organizational unit, or organization; they need not be added to individual principal policies or resource policies.

    Another very handy new IAM feature launch is additional information about the reason for an access denied error message. With this additional information, you can now see which of the relevant access control policies (for example, IAM, resource, SCP, or VPC endpoint) was the cause of the denial. As of now, this new IAM feature is supported by more than 50% of all AWS services in the AWS SDK and AWS Command Line Interface, and a fast-growing number in the AWS Management Console. We will continue to add support for this capability across services, as well as add more features that are designed to make the journey to least privilege simpler.

    IAM Access Analyzer

    AWS Identity and Access Management (IAM) Access Analyzer provides actionable recommendations to set secure and functional permissions. Access Analyzer introduced the ability to preview the impact of policy changes before deployment and added over 100 policy checks for correctness. Both of these enhancements are integrated into the console and are also available through APIs. Access Analyzer also provides findings for external access allowed by resource policies for many services, including a previous launch in which IAM Access Analyzer was directly integrated into the Amazon S3 management console.

    IAM Access Analyzer also launched the ability to generate fine-grained policies based on analyzing past AWS CloudTrail activity. This feature provides a great new capability for DevOps teams or central security teams to scope down policies to just the permissions needed, making it simpler to implement least privilege permissions. IAM Access Analyzer launched further enhancements to expand policy checks, and the ability to generate a sample least-privilege policy from past activity was expanded beyond the account level to include an analysis of principal behavior within the entire organization by analyzing log activity stored in AWS CloudTrail.

    AWS Resource Access Manager

    AWS Resource Access Manager (AWS RAM) helps you securely share your resources across unrelated AWS accounts within your organization or organizational units (OUs) in AWS Organizations. Now you can also share your resources with IAM roles and IAM users for supported resource types. This update enables more granular access using managed permissions that you can use to define access to shared resources. In addition to the default managed permission defined for each shareable resource type, you now have more flexibility to choose which permissions to grant to whom for resource types that support additional managed permissions. Additionally, AWS RAM added support for global resource types, enabling you to provision a global resource once, and share that resource across your accounts. A global resource is one that can be used in multiple AWS Regions; the first example of a global resource is found in AWS Cloud WAN, currently in preview as of this publication. AWS RAM helps you more securely share an AWS Cloud WAN core network, which is a managed network containing AWS and on-premises networks. With AWS RAM global resource sharing, you can use the Cloud WAN core network to centrally operate a unified global network across Regions and accounts.

    AWS Directory Service

    AWS Directory Service for Microsoft Active Directory, also known as AWS Managed Microsoft Active Directory (AD), was updated to automatically provide domain controller and directory utilization metrics in Amazon CloudWatch for new and existing directories. Analyzing these utilization metrics helps you quantify your average and peak load times to identify the need for additional domain controllers. With this, you can define the number of domain controllers to meet your performance, resilience, and cost requirements.

    Amazon Cognito

    Amazon Cognito identity pools (federated identities) was updated to enable you to use attributes from social and corporate identity providers to make access control decisions and simplify permissions management in AWS resources. In Amazon Cognito, you can choose predefined attribute-tag mappings, or you can create custom mappings using the attributes from social and corporate providers’ access and ID tokens, or SAML assertions. You can then reference the tags in an IAM permissions policy to implement attribute-based access control (ABAC) and manage access to your AWS resources. Amazon Cognito also launched a new console experience for user pools and now supports targeted sign out through refresh token revocation.

    Governance, control, and logging services

    There were a number of important releases in 2021 in the areas of governance, control, and logging services.

    AWS Organizations

    AWS Organizations added a number of important import features and integrations during 2021. Security-relevant services like Amazon Detective, Amazon Inspector, and Amazon Virtual Private Cloud (Amazon VPC) IP Address Manager (IPAM), as well as others like Amazon DevOps Guru, launched integrations with Organizations. Others like AWS SSO and AWS License Manager upgraded their Organizations support by adding support for a Delegated Administrator account, reducing the need to use the management account for operational tasks. Amazon EC2 and EC2 Image Builder took advantage of the account grouping capabilities provided by Organizations to allow cross-account sharing of Amazon Machine Images (AMIs) (for more details, see the Amazon EC2 section later in this post). Organizations also got an updated console, increased quotas for tag policies, and provided support for the launch of an API that allows for programmatic creation and maintenance of AWS account alternate contacts, including the very important security contact (although that feature doesn’t require Organizations). For more information on the value of using the security contact for your accounts, see the blog post Update the alternate security contact across your AWS accounts for timely security notifications.

    AWS Control Tower

    2021 was also a good year for AWS Control Tower, beginning with an important launch of the ability to take over governance of existing OUs and accounts, as well as bulk update of new settings and guardrails with a single button click or API call. Toward the end of 2021, AWS Control Tower added another valuable enhancement that allows it to work with a broader set of customers and use cases, namely support for nested OUs within an organization.

    AWS CloudFormation Guard 2.0

    Another important milestone in 2021 for creating and maintaining a well-governed cloud environment was the re-launch of CloudFormation Guard as Cfn-Guard 2.0. This launch was a major overhaul of the Cfn-Guard domain-specific language (DSL), a DSL designed to provide the ability to test infrastructure-as-code (IaC) templates such as CloudFormation and Terraform to make sure that they conform with a set of constraints written in the DSL by a central team, such as a security organization or network management team.

    This approach provides a powerful new middle ground between the older security models of prevention (which provide developers only an access denied message, and often can’t distinguish between an acceptable and an unacceptable use of the same API) and a detect and react model (when undesired states have already gone live). The Cfn-Guard 2.0 model gives builders the freedom to build with IaC, while allowing central teams to have the ability to reject infrastructure configurations or changes that don’t conform to central policies—and to do so with completely custom error messages that invite dialog between the builder team and the central team, in case the rule is unnuanced and needs to be refined, or if a specific exception needs to be created.

    For example, a builder team might be allowed to provision and attach an internet gateway to a VPC, but the team can do this only if the routes to the internet gateway are limited to a certain pre-defined set of CIDR ranges, such as the public addresses of the organization’s branch offices. It’s not possible to write an IAM policy that takes into account the CIDR values of a VPC route table update, but you can write a Cfn-Guard 2.0 rule that allows the creation and use of an internet gateway, but only with a defined and limited set of IP addresses.

    AWS Systems Manager Incident Manager

    An important launch that security professionals should know about is AWS Systems Manager Incident Manager. Incident Manager provides a number of powerful capabilities for managing incidents of any kind, including operational and availability issues but also security issues. With Incident Manager, you can automatically take action when a critical issue is detected by an Amazon CloudWatch alarm or Amazon EventBridge event. Incident Manager runs pre-configured response plans to engage responders by using SMS and phone calls, can enable chat commands and notifications using AWS Chatbot, and runs automation workflows with AWS Systems Manager Automation runbooks. The Incident Manager console integrates with AWS Systems Manager OpsCenter to help you track incidents and post-incident action items from a central place that also synchronizes with third-party management tools such as Jira Service Desk and ServiceNow. Incident Manager enables cross-account sharing of incidents using AWS RAM, and provides cross-Region replication of incidents to achieve higher availability.

    AWS CloudTrail

    AWS CloudTrail added some great new logging capabilities in 2021, including logging data-plane events for Amazon DynamoDB and Amazon Elastic Block Store (Amazon EBS) direct APIs (direct APIs allow access to EBS snapshot content through a REST API). CloudTrail also got further enhancements to its machine-learning based CloudTrail Insights feature, including a new one called ErrorRate Insights.

    Amazon S3

    Amazon Simple Storage Service (Amazon S3) is one of the most important services at AWS, and its steady addition of security-related enhancements is always big news. Here are the 2021 highlights.

    Access Points aliases

    Amazon S3 introduced a new feature, Amazon S3 Access Points aliases. With Amazon S3 Access Points aliases, you can make the access points backwards-compatible with a large amount of existing code that is programmed to interact with S3 buckets rather than access points.

    To understand the importance of this launch, we have to go back to 2019 to the launch of Amazon S3 Access Points. Access points are a powerful mechanism for managing S3 bucket access. They provide a great simplification for managing and controlling access to shared datasets in S3 buckets. You can create up to 1,000 access points per Region within each of your AWS accounts. Although bucket access policies remain fully enforced, you can delegate access control from the bucket to its access points, allowing for distributed and granular control. Each access point enforces a customizable policy that can be managed by a particular workgroup, while also avoiding the problem of bucket policies needing to grow beyond their maximum size. Finally, you can also bind an access point to a particular VPC for its lifetime, to prevent access directly from the internet.

    With the 2021 launch of Access Points aliases, Amazon S3 now generates a unique DNS name, or alias, for each access point. The Access Points aliases look and acts just like an S3 bucket to existing code. This means that you don’t need to make changes to older code to use Amazon S3 Access Points; just substitute an Access Points aliases wherever you previously used a bucket name. As a security team, it’s important to know that this flexible and powerful administrative feature is backwards-compatible and can be treated as a drop-in replacement in your various code bases that use Amazon S3 but haven’t been updated to use access point APIs. In addition, using Access Points aliases adds a number of powerful security-related controls, such as permanent binding of S3 access to a particular VPC.

    Bucket Keys

    Amazon S3 launched support for S3 Inventory and S3 Batch Operations to identify and copy objects to use S3 Bucket Keys, which can help reduce the costs of server-side encryption (SSE) with AWS Key Management Service (AWS KMS).

    S3 Bucket Keys were launched at the end of 2020, another great launch that security professionals should know about, so here is an overview in case you missed it. S3 Bucket Keys are data keys generated by AWS KMS to provide another layer of envelope encryption in which the outer layer (the S3 Bucket Key) is cached by S3 for a short period of time. This extra key layer increases performance and reduces the cost of requests to AWS KMS. It achieves this by decreasing the request traffic from Amazon S3 to AWS KMS from a one-to-one model—one request to AWS KMS for each object written to or read from Amazon S3—to a one-to-many model using the cached S3 Bucket Key. The S3 Bucket Key is never stored persistently in an unencrypted state outside AWS KMS, and so Amazon S3 ultimately must always return to AWS KMS to encrypt and decrypt the S3 Bucket Key, and thus, the data. As a result, you still retain control of the key hierarchy and resulting encrypted data through AWS KMS, and are still able to audit Amazon S3 returning periodically to AWS KMS to refresh the S3 Bucket Keys, as logged in CloudTrail.

    Returning to our review of 2021, S3 Bucket Keys gained the ability to use Amazon S3 Inventory and Amazon S3 Batch Operations automatically to migrate objects from the higher cost, slightly lower-performance SSE-KMS model to the lower-cost, higher-performance S3 Bucket Keys model.

    Simplified ownership and access management

    The final item from 2021 for Amazon S3 is probably the most important of all. Last year was the year that Amazon S3 achieved fully modernized object ownership and access management capabilities. You can now disable access control lists to simplify ownership and access management for data in Amazon S3.

    To understand this launch, we need to go in time to the origins of Amazon S3, which is one of the oldest services in AWS, created even before IAM was launched in 2011. In those pre-IAM days, a storage system like Amazon S3 needed to have some kind of access control model, so Amazon S3 invented its own: Amazon S3 access control lists (ACLs). Using ACLs, you could add access permissions down to the object level, but only with regard to access by other AWS account principals (the only kind of identity that was available at the time), or public access (read-only or read-write) to an object. And in this model, objects were always owned by the creator of the object, not the bucket owner.

    After IAM was introduced, Amazon S3 added the bucket policy feature, a type of resource policy that provides the rich features of IAM, including full support for all IAM principals (users and roles), time-of-day conditions, source IP conditions, ability to require encryption, and more. For many years, Amazon S3 access decisions have been made by combining IAM policy permissions and ACL permissions, which has served customers well. But the object-writer-is-owner issue has often caused friction. The good news for security professionals has been that a deny by either type of access control type overrides an allow by the other, so there were no security issues with this bi-modal approach. The challenge was that it could be administratively difficult to manage both resource policies—which exist at the bucket and access point level—and ownership and ACLs—which exist at the object level. Ownership and ACLs might potentially impact the behavior of only a handful of objects, in a bucket full of millions or billions of objects.

    With the features released in 2021, Amazon S3 has removed these points of friction, and now provides the features needed to reduce ownership issues and to make IAM-based policies the only access control system for a specified bucket. The first step came in 2020 with the ability to make object ownership track bucket ownership, regardless of writer. But that feature applied only to newly-written objects. The final step is the 2021 launch we’re highlighting here: the ability to disable at the bucket level the evaluation of all existing ACLs—including ownership and permissions—effectively nullifying all object ACLs. From this point forward, you have the mechanisms you need to govern Amazon S3 access with a combination of S3 bucket policies, S3 access point policies, and (within the same account) IAM principal policies, without worrying about legacy models of ACLs and per-object ownership.

    Additional database and storage service features

    AWS Backup Vault Lock

    AWS Backup added an important new additional layer for backup protection with the availability of AWS Backup Vault Lock. A vault lock feature in AWS is the ability to configure a storage policy such that even the most powerful AWS principals (such as an account or Org root principal) can only delete data if the deletion conforms to the preset data retention policy. Even if the credentials of a powerful administrator are compromised, the data stored in the vault remains safe. Vault lock features are extremely valuable in guarding against a wide range of security and resiliency risks (including accidental deletion), notably in an era when ransomware represents a rising threat to data.

    Prior to AWS Backup Vault Lock, AWS provided the extremely useful Amazon S3 and Amazon S3 Glacier vault locking features, but these previous vaulting features applied only to the two Amazon S3 storage classes. AWS Backup, on the other hand, supports a wide range of storage types and databases across the AWS portfolio, including Amazon EBS, Amazon Relational Database Service (Amazon RDS) including Amazon Aurora, Amazon DynamoDB, Amazon Neptune, Amazon DocumentDB, Amazon Elastic File System (Amazon EFS), Amazon FSx for Lustre, Amazon FSx for Windows File Server, Amazon EC2, and AWS Storage Gateway. While built on top of Amazon S3, AWS Backup even supports backup of data stored in Amazon S3. Thus, this new AWS Backup Vault Lock feature effectively serves as a vault lock for all the data from most of the critical storage and database technologies made available by AWS.

    Finally, as a bonus, AWS Backup added two more features in 2021 that should delight security and compliance professionals: AWS Backup Audit Manager and compliance reporting.

    Amazon DynamoDB

    Amazon DynamoDB added a long-awaited feature: data-plane operations integration with AWS CloudTrail. DynamoDB has long supported the recording of management operations in CloudTrail—including a long list of operations like CreateTable, UpdateTable, DeleteTable, ListTables, CreateBackup, and many others. What has been added now is the ability to log the potentially far higher volume of data operations such as PutItem, BatchWriteItem, GetItem, BatchGetItem, and DeleteItem. With this launch, full database auditing became possible. In addition, DynamoDB added more granular control of logging through DynamoDB Streams filters. This feature allows users to vary the recording in CloudTrail of both control plane and data plane operations, at the table or stream level.

    Amazon EBS snapshots

    Let’s turn now to a simple but extremely useful feature launch affecting Amazon Elastic Block Store (Amazon EBS) snapshots. In the past, it was possible to accidently delete an EBS snapshot, which is a problem for security professionals because data availability is a part of the core security triad of confidentiality, integrity, and availability. Now you can manage that risk and recover from accidental deletions of your snapshots by using Recycle Bin. You simply define a retention policy that applies to all deleted snapshots, and then you can define other more granular policies, for example using longer retention periods based on snapshot tag values, such as stage=prod. Along with this launch, the Amazon EBS team announced EBS Snapshots Archive, a major price reduction for long-term storage of snapshots.

    AWS Certificate Manager Private Certificate Authority

    2021 was a big year for AWS Certificate Manager (ACM) Private Certificate Authority (CA) with the following updates and new features:

    Network and application protection

    We saw a lot of enhancements in network and application protection in 2021 that will help you to enforce fine-grained security policies at important network control points across your organization. The services and new capabilities offer flexible solutions for inspecting and filtering traffic to help prevent unauthorized resource access.

    AWS WAF

    AWS WAF launched AWS WAF Bot Control, which gives you visibility and control over common and pervasive bots that consume excess resources, skew metrics, cause downtime, or perform other undesired activities. The Bot Control managed rule group helps you monitor, block, or rate-limit pervasive bots, such as scrapers, scanners, and crawlers. You can also allow common bots that you consider acceptable, such as status monitors and search engines. AWS WAF also added support for custom responses, managed rule group versioning, in-line regular expressions, and Captcha. The Captcha feature has been popular with customers, removing another small example of “undifferentiated work” for customers.

    AWS Shield Advanced

    AWS Shield Advanced now automatically protects web applications by blocking application layer (L7) DDoS events with no manual intervention needed by you or the AWS Shield Response Team (SRT). When you protect your resources with AWS Shield Advanced and enable automatic application layer DDoS mitigation, Shield Advanced identifies patterns associated with L7 DDoS events and isolates this anomalous traffic by automatically creating AWS WAF rules in your web access control lists (ACLs).

    Amazon CloudFront

    In other edge networking news, Amazon CloudFront added support for response headers policies. This means that you can now add cross-origin resource sharing (CORS), security, and custom headers to HTTP responses returned by your CloudFront distributions. You no longer need to configure your origins or use custom Lambda@Edge or CloudFront Functions to insert these headers.

    CloudFront Functions were another great 2021 addition to edge computing, providing a simple, inexpensive, and yet highly secure method for running customer-defined code as part of any CloudFront-managed web request. CloudFront functions allow for the creation of very efficient, fine-grained network access filters, such the ability to block or allow web requests at a region or city level.

    Amazon Virtual Private Cloud and Route 53

    Amazon Virtual Private Cloud (Amazon VPC) added more-specific routing (routing subnet-to-subnet traffic through a virtual networking device) that allows for packet interception and inspection between subnets in a VPC. This is particularly useful for highly-available, highly-scalable network virtual function services based on Gateway Load Balancer, including both AWS services like AWS Network Firewall, as well as third-party networking services such as the recently announced integration between AWS Firewall Manager and Palo Alto Networks Cloud Next Generation Firewall, powered by Gateway Load Balancer.

    Another important set of enhancements to the core VPC experience came in the area of VPC Flow Logs. Amazon VPC launched out-of-the-box integration with Amazon Athena. This means with a few clicks, you can now use Athena to query your VPC flow logs delivered to Amazon S3. Additionally, Amazon VPC launched three associated new log features that make querying more efficient by supporting Apache Parquet, Hive-compatible prefixes, and hourly partitioned files.

    Following Route 53 Resolver’s much-anticipated launch of DNS logging in 2020, the big news for 2021 was the launch of its DNS Firewall capability. Route 53 Resolver DNS Firewall lets you create “blocklists” for domains you don’t want your VPC resources to communicate with, or you can take a stricter, “walled-garden” approach by creating “allowlists” that permit outbound DNS queries only to domains that you specify. You can also create alerts for when outbound DNS queries match certain firewall rules, allowing you to test your rules before deploying for production traffic. Route 53 Resolver DNS Firewall launched with two managed domain lists—malware domains and botnet command and control domains—enabling you to get started quickly with managed protections against common threats. It also integrated with Firewall Manager (see the following section) for easier centralized administration.

    AWS Network Firewall and Firewall Manager

    Speaking of AWS Network Firewall and Firewall Manager, 2021 was a big year for both. Network Firewall added support for AWS Managed Rules, which are groups of rules based on threat intelligence data, to enable you to stay up to date on the latest security threats without writing and maintaining your own rules. AWS Network Firewall features a flexible rules engine enabling you to define firewall rules that give you fine-grained control over network traffic. As of the launch in late 2021, you can enable managed domain list rules to block HTTP and HTTPS traffic to domains identified as low-reputation, or that are known or suspected to be associated with malware or botnets. Prior to that, another important launch was new configuration options for rule ordering and default drop, making it simpler to write and process rules to monitor your VPC traffic. Also in 2021, Network Firewall announced a major regional expansion following its initial launch in 2020, and a range of compliance achievements and eligibility including HIPAA, PCI DSS, SOC, and ISO.

    Firewall Manager also had a strong 2021, adding a number of additional features beyond its initial core area of managing network firewalls and VPC security groups that provide centralized, policy-based control over many other important network security capabilities: Amazon Route 53 Resolver DNS Firewall configurations, deployment of the new AWS WAF Bot Control, monitoring of VPC routes for AWS Network Firewall, AWS WAF log filtering, AWS WAF rate-based rules, and centralized logging of AWS Network Firewall logs.

    Elastic Load Balancing

    Elastic Load Balancing now supports forwarding traffic directly from Network Load Balancer (NLB) to Application Load Balancer (ALB). With this important new integration, you can take advantage of many critical NLB features such as support for AWS PrivateLink and exposing static IP addresses for applications that still require ALB.

    In addition, Network Load Balancer now supports version 1.3 of the TLS protocol. This adds to the existing TLS 1.3 support in Amazon CloudFront, launched in 2020. AWS plans to add TLS 1.3 support for additional services.

    The AWS Networking team also made Amazon VPC private NAT gateways available in both AWS GovCloud (US) Regions. The expansion into the AWS GovCloud (US) Regions enables US government agencies and contractors to move more sensitive workloads into the cloud by helping them to address certain regulatory and compliance requirements.

    Compute

    Security professionals should also be aware of some interesting enhancements in AWS compute services that can help improve their organization’s experience in building and operating a secure environment.

    Amazon Elastic Compute Cloud (Amazon EC2) launched the Global View on the console to provide visibility to all your resources across Regions. Global View helps you monitor resource counts, notice abnormalities sooner, and find stray resources. A few days into 2022, another simple but extremely useful EC2 launch was the new ability to obtain instance tags from the Instance Metadata Service (IMDS). Many customers run code on Amazon EC2 that needs to introspect about the EC2 tags associated with the instance and then change its behavior depending on the content of the tags. Prior to this launch, you had to associate an EC2 role and call the EC2 API to get this information. That required access to API endpoints, either through a NAT gateway or a VPC endpoint for Amazon EC2. Now, that information can be obtained directly from the IMDS, greatly simplifying a common use case.

    Amazon EC2 launched sharing of Amazon Machine Images (AMIs) with AWS Organizations and Organizational Units (OUs). Previously, you could share AMIs only with specific AWS account IDs. To share AMIs within AWS Organizations, you had to explicitly manage sharing of AMIs on an account-by-account basis, as they were added to or removed from AWS Organizations. With this new feature, you no longer have to update your AMI permissions because of organizational changes. AMI sharing is automatically synchronized when organizational changes occur. This feature greatly helps both security professionals and governance teams to centrally manage and govern AMIs as you grow and scale your AWS accounts. As previously noted, this feature was also added to EC2 Image Builder. Finally, Amazon Data Lifecycle Manager, the tool that manages all your EBS volumes and AMIs in a policy-driven way, now supports automatic deprecation of AMIs. As a security professional, you will find this helpful as you can set a timeline on your AMIs so that, if the AMIs haven’t been updated for a specified period of time, they will no longer be considered valid or usable by development teams.

    Looking ahead

    In 2022, AWS continues to deliver experiences that meet administrators where they govern, developers where they code, and applications where they run. We will continue to summarize important launches in future blog posts. If you’re interested in learning more about AWS services, join us for AWS re:Inforce, the AWS conference focused on cloud security, identity, privacy, and compliance. AWS re:Inforce 2022 will take place July 26–27 in Boston, MA. Registration is now open. Register now with discount code SALxUsxEFCw to get $150 off your full conference pass to AWS re:Inforce. For a limited time only and while supplies last. We look forward to seeing you there!

    To stay up to date on the latest product and feature launches and security use cases, be sure to read the What’s New with AWS announcements (or subscribe to the RSS feed) and the AWS Security Blog.

     
    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

    Want more AWS Security news? Follow us on Twitter.

    Author

    Marta Taggart

    Marta is a Seattle-native and Senior Product Marketing Manager in AWS Security Product Marketing, where she focuses on data protection services. Outside of work you’ll find her trying to convince Jack, her rescue dog, not to chase squirrels and crows (with limited success).

    Mark Ryland

    Mark Ryland

    Mark is the director of the Office of the CISO for AWS. He has over 30 years of experience in the technology industry and has served in leadership roles in cybersecurity, software engineering, distributed systems, technology standardization and public policy. Previously, he served as the Director of Solution Architecture and Professional Services for the AWS World Public Sector team.

    How Ribbon Communications Built a Scalable, Resilient Robocall Mitigation Platform

    Post Syndicated from Siva Rajamani original https://aws.amazon.com/blogs/architecture/how-ribbon-communications-built-a-scalable-resilient-robocall-mitigation-platform/

    Ribbon Communications provides communications software, and IP and optical networking end-to-end solutions that deliver innovation, unparalleled scale, performance, and agility to service providers and enterprise.

    Ribbon Communications is helping customers modernize their networks. In today’s data-hungry, 24/7 world, this equates to improved competitive positioning and business outcomes. Companies are migrating from on-premises equipment for telephony services and looking for equivalent as a service (aaS) offerings. But these solutions must still meet the stringent resiliency, availability, performance, and regulatory requirements of a telephony service.

    The telephony world is inundated with robocalls. In the United States alone, there were an estimated 50.5 billion robocalls in 2021! In this blog post, we describe the Ribbon Identity Hub – a holistic solution for robocall mitigation. The Ribbon Identity Hub enables services that sign and verify caller identity, which is compliant to the ATIS standards under the STIR/SHAKEN framework. It also evaluates and scores calls for the probability of nuisance and fraud.

    Ribbon Identity Hub is implemented in Amazon Web Services (AWS). It is a fully managed service for telephony service providers and enterprises. The solution is secure, multi-tenant, automatic scaling, and multi-Region, and enables Ribbon to offer managed services to a wide range of telephony customers. Ribbon ensures resiliency and performance with efficient use of resources in the telephony environment, where load ratios between busy and idle time can exceed 10:1.

    Ribbon Identity Hub

    The Ribbon Identity Hub services are separated into a data (call-transaction) plane, and a control plane.

    Data plane (call-transaction)

    The call-transaction processing is typically invoked on a per-call-setup basis where availability, resilience, and performance predictability are paramount. Additionally, due to high variability in load, automatic scaling is a prerequisite.
    Figure 1. Data plane architecture

    Figure 1. Data plane architecture

    Several AWS services come together in a solution that meets all these important objectives:

    1. Amazon Elastic Container Service (ECS): The ECS services are set up for automatic scaling and span two Availability Zones. This provides the horizontal scaling capability, the self-healing capacity, and the resiliency across Availability Zones.
    2. Elastic Load Balancing – Application Load Balancer (ALB): This provides the ability to distribute incoming traffic to ECS services as the target. In addition, it also offers:
      • Seamless integration with the ECS Auto Scaling group. As the group grows, traffic is directed to the new instances only when they are ready. As traffic drops, traffic is drained from the target instances for graceful scale down.
      • Full support for canary and linear upgrades with zero downtime. Maintains full-service availability without any changes or even perception for the client devices.
    3. Amazon Simple Storage Service (S3): Transaction detail records associated with call-related requests must be securely and reliably maintained for over a year due to billing and other contractual obligations. Amazon S3 simplifies this task with high durability, lifecycle rules, and varied controls for retention.
    4. Amazon DynamoDB: Building resilient services is significantly easier when the compute processing can be stateless. Amazon DynamoDB facilitates such stateless architectures without compromise. Coupled with the availability of the Amazon DynamoDB Accelerator (DAX) caching layer, the solution can meet the extreme low latency operation requirements.
    5. AWS Key Management Service (KMS): Certain tenant configuration is highly confidential and requires elevated protection. Furthermore, the data is part of the state that must be recovered across Regions in disaster recovery scenarios. To meet the security requirements, the KMS is used for envelope encryption using per-tenant keys. Multi-Region KMS keys facilitates the secure availability of this state across Regions without the need for application-level intervention when replicating encrypted data.
    6. Amazon Route 53: For telephony services, any non-transient service failure is unacceptable. In addition to providing high degree of resiliency through Multi-AZ architecture, Identity Hub also provides Regional level high availability through its multi-Region active-active architecture. Route 53 with health checks provides for dynamic rerouting of requests within minutes to alternate Regions.

    Control plane

    The Identity Hub control plane is used for customer configuration, status, and monitoring. The API is REST-based. Since this is not used on a call-by-call basis, the requirements around latency and performance are less stringent, though the requirements around high resiliency and dynamic scaling still apply. In this area, ease of implementation and maintainability are key.

    Figure 2. Control plane architecture

    Figure 2. Control plane architecture

    The following AWS services implement our control plane:

    1. Amazon API Gateway: Coupled with a custom authenticator, the API Gateway handles all the REST API credential verification and routing. Implementation of an API is transformed into implementing handlers for each resource, which is the application core of the API.
    2. AWS Lambda: All the REST API handlers are written as Lambda functions. By using the Lambda’s serverless and concurrency features, the application automatically gains self-healing and auto-scaling capabilities. There is also a significant cost advantage as billing is per millisecond of actual compute time used. This is significant for a control plane where usage is typically sparse and unpredictable.
    3. Amazon DynamoDB: A stateless architecture with Lambda and API Gateway, all persistent state must be stored in an external database. The database must match the resilience and auto-scaling characteristics of the rest of the control plane. DynamoDB easily fits the requirements here.

    The customer portal, in addition to providing the user interface for control plane REST APIs, also delivers a rich set of user-customizable dashboards and reporting capability. Here again, the availability of various AWS services simplifies the implementation, and remains non-intrusive to the central call-transaction processing.

    Services used here include:

    1. AWS Glue: Enables extraction and transformation of raw transaction data into a format useful for reporting and dashboarding. AWS Glue is particularly useful here as the data available is regularly expanding, and the use cases for the reporting and dashboarding increase.
    2. Amazon QuickSight: Provides all the business intelligence (BI) functionality, including the ability for Ribbon to offer separate author and reader access to their users, and implements tenant-based access separation.

    Conclusion

    Ribbon has successfully deployed Identity Hub to enable cloud hosted telephony services to mitigate robocalls. Telephony requirements around resiliency, performance, and capacity were not compromised. Identity Hub offers the benefits of a 24/7 fully managed service requiring no additional customer on-premises equipment.

    Choosing AWS services for Identity Hub gives Ribbon the ability to scale and meet future growth. The ability to dynamically scale the service in and out also brings significant cost advantages in telephony applications where busy hour traffic is significantly higher than idle time traffic. In addition, the availability of global AWS services facilitates the deployment of services in customer-local geographic locations to meet performance requirements or local regulatory compliance.