Post Syndicated from original https://lwn.net/Articles/897226/
Security updates have been issued by Debian (glib2.0, librecad, and php-horde-mime-viewer), Fedora (vim), and Ubuntu (freerdp2, ruby2.3, ruby2.5, ruby2.7, ruby3.0, and vim).
Post Syndicated from original https://lwn.net/Articles/897226/
Security updates have been issued by Debian (glib2.0, librecad, and php-horde-mime-viewer), Fedora (vim), and Ubuntu (freerdp2, ruby2.3, ruby2.5, ruby2.7, ruby3.0, and vim).
Post Syndicated from Jocelyn Woolbright original https://blog.cloudflare.com/lets-celebrate-the-8th-anniversary-of-project-galileo/
We started Project Galileo in 2014 with the simple idea that organizations that work in vulnerable yet essential areas of human rights and democracy building should not be taken down because of cyber attacks. In the past eight years, this idea has grown to more than just keeping them secure from a DDoS attack, but also how to foster collaboration with civil society to offer more tools and support to these groups. In March 2022, after the war in Ukraine started, we saw an increase in applications to Project Galileo by 177%.
Read ahead for details on all of our eighth anniversary announcements:
This year, we are excited to welcome two new partners, International Media Support and CyberPeace Institute. As we introduce new partners, we are able to expand the project to protect a range of groups on the Internet. With this, we currently protect 1,900+ organizations in 111 countries.
With almost three years working on Project Galileo at Cloudflare, I get a front row seat to how we use security tools to protect the most vulnerable on the Internet. From journalism groups in Brazil reporting on environmental issues to social justice organizations in the United States to activists in authoritarian countries, we see a range of voices that come to Cloudflare for protection.
The anniversary of the project is one of my favorite times of the year, as it gives us the opportunity to show the world a glimpse of what we see on a daily basis. With the anniversary, it also gives us time to reflect on lessons learned and how we can improve the project.
One of the most important lessons we have learned about Project Galileo is that in a time of crisis, whether it be the spread of COVID-19 and shift to remote work or geopolitical conflicts, we are able to quickly mobilize to offer our assistance. One way we do this is to leverage our partnerships with civil society to offer our security tools and technical expertise to those who need help to keep their online platforms secure and reliable.
This became clear at the end of February 2022 and the start of the Russian invasion of Ukraine.
After the war in Ukraine started, applications to the project increased by 177% in March 2022. Since then, we onboarded 43 organizations in Ukraine to Project Galileo. In the region, we protect 116 organizations with 62 organizations onboarded to the project during the crisis, this includes organizations in Ukraine. Many of these organizations are working in journalism and reporting on the ground in Kyiv, human rights activists that are assisting refugees fleeing the country, and groups who have built applications to alert users of incoming air raids.
We have seen how partnerships between civil society, governments, and private sector companies have given us the ability to provide a swift response in providing support to Ukraine.
We see this in the form of donations of security services to ensure that people on the ground have access to information. There has been a focus on the conflict in Ukraine primarily on how to protect organizations that work in human rights. But, many civil society groups that have been working to provide assistance may have been overlooked in the digital security context. Many times, civil society does not get as many resources to protect themselves, and we strive to provide our services to human rights defenders, but also those who support them.
We have learned in the past few months that collaboration in a time of crisis is essential to responsibly provide our protections under the project. Any Ukrainian organizations that are facing attack can apply for free protection under Project Galileo by visiting www.cloudflare.com/galileo, and we will expedite their review and approval.
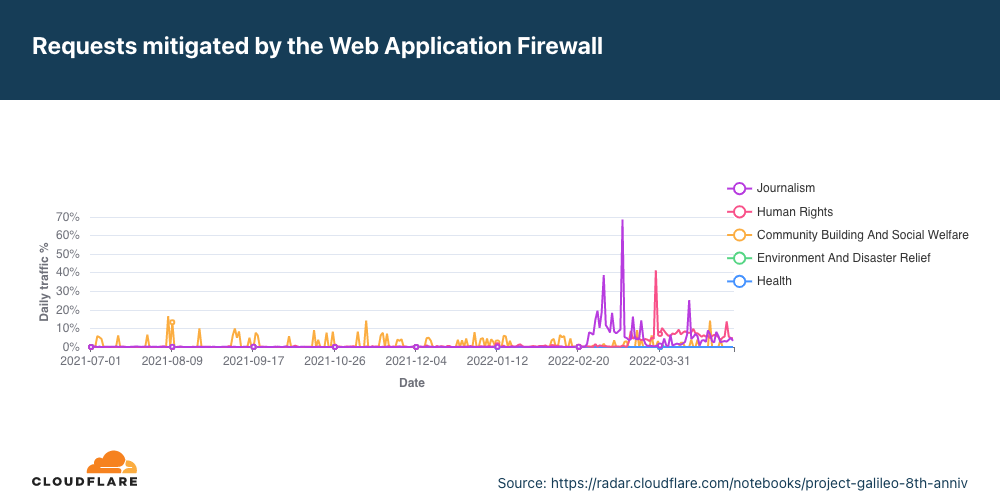
For the Project Galileo 8th anniversary, we wanted to identify the types of attacks these groups face to better equip researchers, civil society, and organizations that are targeted with best practices for safeguarding their websites and internal data.
We created a Radar dashboard to focus on attacks against organizations in areas such as human rights, journalism, and community building groups. We onboarded a range of organizations in Ukraine and neighboring countries during the ongoing Russian invasion.
Learn more about the attacks we see against vulnerable groups protected under Project Galileo with an additional blog post and Radar dashboard tomorrow.
Project Galileo has grown to support more than 1,900 organizations. These organizations typically fall into two categories. The first are organizations that are familiar with the security landscape and the Cloudflare tools they need to keep their organization secure. The second, which is a majority of organizations we protect under the project, are not familiar with the threat landscape and do not have a dedicated IT staff.
We know too well that organizations that work to support democracy, accountability, and human rights face an increased rate of cyber attacks because of the sensitive nature of their work. Many times, organizations come to Cloudflare because they come under a cyber attack and need our help with mitigation and getting back online. Unfortunately, we see applications like this come in every day for Project Galileo.
With this, we wanted to create a new resource to help these organizations on their Cloudflare journey. We are proud to release a new centralized area that organizations protected under our many projects can turn to when they have questions about configurations, product requests, and training on how to keep their organization secure. With tailored videos on security products with a focus on Cloudflare Zero Trust products, we are excited to offer more resources to organizations with very little or no dedicated IT staff, to ensure they stay online and secure from cyber attacks.
Learn more about our Cloudflare Social Impact Project portal and how we built this specifically for organizations protected under our Cloudflare Impact projects this week.
Every year, Cloudflare sponsors Access Now’s RightsCon. RightsCon brings together a broad range of civil society groups and business and public sector stakeholders to talk and learn about digital rights issues. With topics including Internet shutdowns, digital security, privacy, and surveillance, it has it all for a great week of engaging with a range of players in the digital rights space.
This year, we are participating in a variety of events, but particularly excited about a community lab we are hosting with partner organizations like National Democratic Institute, Internews, CyberPeace Institute, and Okta. The session is focused on tools available for at-risk organizations and to learn more on how the private sector and civil society can improve security resources. We’ve learned in the last few years of Project Galileo that we are one part of the broader ecosystem. When it comes to providing tools to organizations, it is important to work together with the many players to find the best way to support organizations online and offline. We hope this session will generate further ideas on how we can work closely with others and earn more on how organizations view security resources.
If you plan to attend RightsCon, please check out our session on Wednesday, June 8, at 12:30 pm ET. More information can be found on the RightsCon website.
As we celebrate the anniversary, we want to highlight many of the organizations protected under the project and how they keep their organization secure from cyber attacks. We value organizations that want to tell their story of the amazing work they do in human rights and community building and how they stay online with Cloudflare. Our goal with telling their stories is to encourage others who may work in similar spaces to take advantage of security tools available to them. Case studies also help other organizations that may be new to the project.
Check out some of their stories on how they use Project Galileo to stay secure from cyber attacks.
As we kick off the 8th anniversary of Project Galileo, we want to thank all of our civil society partners that we work alongside to offer Cloudflare protection. If you are an organization looking for protection under Project Galileo, please visit our website: cloudflare.com/galileo.
Post Syndicated from Jeremy Milk original https://www.backblaze.com/blog/double-redundancy-support-compliance-and-more-with-cloud-replication-now-live/
Cloning is a little bit creepy (Seriously, you can clone your pet now?), but having clones of your data is far from it—creating and storing redundant copies is essential when it comes to protecting your business, complying with regulations, or developing apps. With Backblaze Cloud Replication—now generally available—you can get set up in just a few clicks to automatically copy data across buckets, accounts, or regions.
Join us for a webinar to unbox all the capabilities of Cloud Replication on July 13, 2022 at 10 a.m. PDT with Sam Lu, Product Manager at Backblaze.

Existing customers can start using Cloud Replication immediately by clicking on Cloud Replication within their Backblaze account or via the Backblaze B2 Native API.
Not a Backblaze customer yet? Sign up here. And read on for more details on how this feature can benefit you.
Backblaze Cloud Replication is a new service that allows customers to automatically store to different locations—across regions, across accounts, or in different buckets within the same account. You can set replication rules in a few easy steps.
Once the rules are set on a given bucket, any data uploaded to that bucket will automatically be replicated into the destination bucket you choose.
There are three main reasons you might want to use Cloud Replication:
Keeping redundant copies of your data is the most common use case for Cloud Replication. Enterprises with comprehensive backup strategies, especially as they are increasingly cloud-based, will likely find Cloud Replication immediately applicable. It can help businesses:
Data redundancy has always been a best practice—the gold standard for backup strategies has long been a 3-2-1 approach. The core principles of 3-2-1—keeping at least three copies of your data, on two different media, with one copy off-site—were originally developed for an on-premises world. They still hold true, and today they are being applied in even more robust ways to an increasingly cloud-based world.
Backblaze’s Cloud Replication helps businesses apply the principles of 3-2-1 within a cloud-first or cloud-dominant infrastructure. By storing to multiple regions and/or multiple buckets in the same region, businesses virtually achieve an “off-site” backup—easily and automatically protecting data from natural disasters, political instability, or even run-of-the-mill compliance headaches.
If you have teams, customers, or workflows spread around the world, bringing a copy of your data closer to where work gets done can minimize speed-of-light limitations. Especially for media-heavy teams in industries like game development and postproduction, seconds can make the difference in keeping creative teams operating smoothly. And because you can automate replication and use metadata to track accuracy and process, you can remove some manual steps from the process where errors and data loss tend to crop up.
Version control and smoke testing are nothing new, but when you’re controlling versions of large applications or trying to keep track of what’s live and what’s in testing, you might need a tool with more horsepower and options for customization. Backblaze Cloud Replication can serve these needs.
You can easily replicate objects between buckets dedicated for production, testing, or staging if you need to use the same data and maintain the same metadata. This allows you to observe best practices and automate replication between environments.
If you’re a new customer, click here to sign up for Backblaze B2 Cloud Storage and learn more about Cloud Replication.
The post Double Redundancy, Support Compliance, and More With Cloud Replication: Now Live appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=WrDtabCo0-c
Post Syndicated from Technology Connextras original https://www.youtube.com/watch?v=RpoXFk-ixZc
Post Syndicated from Lucas Pardue original https://blog.cloudflare.com/cloudflare-view-http3-usage/
Today, a cluster of Internet standards were published that rationalize and modernize the definition of HTTP – the application protocol that underpins the web. This work includes updates to, and refactoring of, HTTP semantics, HTTP caching, HTTP/1.1, HTTP/2, and the brand-new HTTP/3. Developing these specifications has been no mean feat and today marks the culmination of efforts far and wide, in the Internet Engineering Task Force (IETF) and beyond. We thought it would be interesting to celebrate the occasion by sharing some analysis of Cloudflare’s view of HTTP traffic over the last 12 months.
However, before we get into the traffic data, for quick reference, here are the new RFCs that you should make a note of and start using:
On May 28, 2021, we enabled QUIC version 1 and HTTP/3 for all Cloudflare customers, using the final “h3” identifier that matches RFC 9114. So although today’s publication is an occasion to celebrate, for us nothing much has changed, and it’s business as usual.
Support for HTTP/3 in the stable release channels of major browsers came in November 2020 for Google Chrome and Microsoft Edge and April 2021 for Mozilla Firefox. In Apple Safari, HTTP/3 support currently needs to be enabled in the “Experimental Features” developer menu in production releases.
A browser and web server typically automatically negotiate the highest HTTP version available. Thus, HTTP/3 takes precedence over HTTP/2. We looked back over the last year to understand HTTP/3 usage trends across the Cloudflare network, as well as analyzing HTTP versions used by traffic from leading browser families (Google Chrome, Mozilla Firefox, Microsoft Edge, and Apple Safari), major search engine indexing bots, and bots associated with some popular social media platforms. The graphs below are based on aggregate HTTP(S) traffic seen globally by the Cloudflare network, and include requests for website and application content across the Cloudflare customer base between May 7, 2021, and May 7, 2022. We used Cloudflare bot scores to restrict analysis to “likely human” traffic for the browsers, and to “likely automated” and “automated” for the search and social bots.
Overall, HTTP/2 still comprises the majority of the request traffic for Cloudflare customer content, as clearly seen in the graph below. After remaining fairly consistent through 2021, HTTP/2 request volume increased by approximately 20% heading into 2022. HTTP/1.1 request traffic remained fairly flat over the year, aside from a slight drop in early December. And while HTTP/3 traffic initially trailed HTTP/1.1, it surpassed it in early July, growing steadily and roughly doubling in twelve months.

Digging into just HTTP/3 traffic, the graph below shows the trend in daily aggregate request volume over the last year for HTTP/3 requests made by the surveyed browser families. Google Chrome (orange line) is far and away the leading browser, with request volume far outpacing the others.
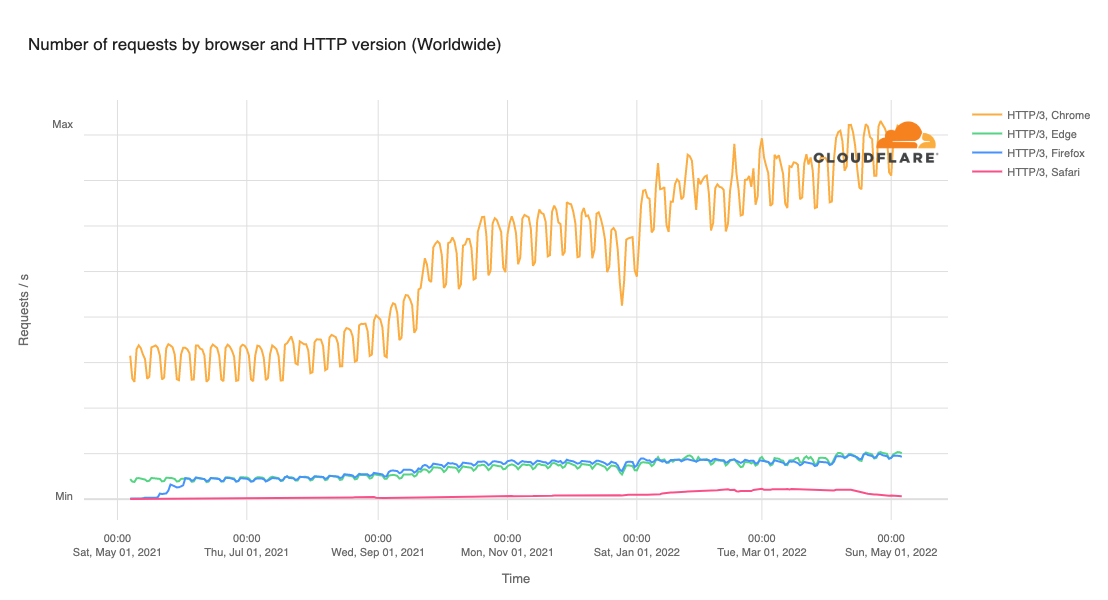
Below, we remove Chrome from the graph to allow us to more clearly see the trending across other browsers. Likely because it is also based on the Chromium engine, the trend for Microsoft Edge closely mirrors Chrome. As noted above, Mozilla Firefox first enabled production support in version 88 in April 2021, making it available by default by the end of May. The increased adoption of that updated version during the following month is clear in the graph as well, as HTTP/3 request volume from Firefox grew rapidly. HTTP/3 traffic from Apple Safari increased gradually through April, suggesting growth in the number of users enabling the experimental feature or running a Technology Preview version of the browser. However, Safari’s HTTP/3 traffic has subsequently dropped over the last couple of months. We are not aware of any specific reasons for this decline, but our most recent observations indicate HTTP/3 traffic is recovering.
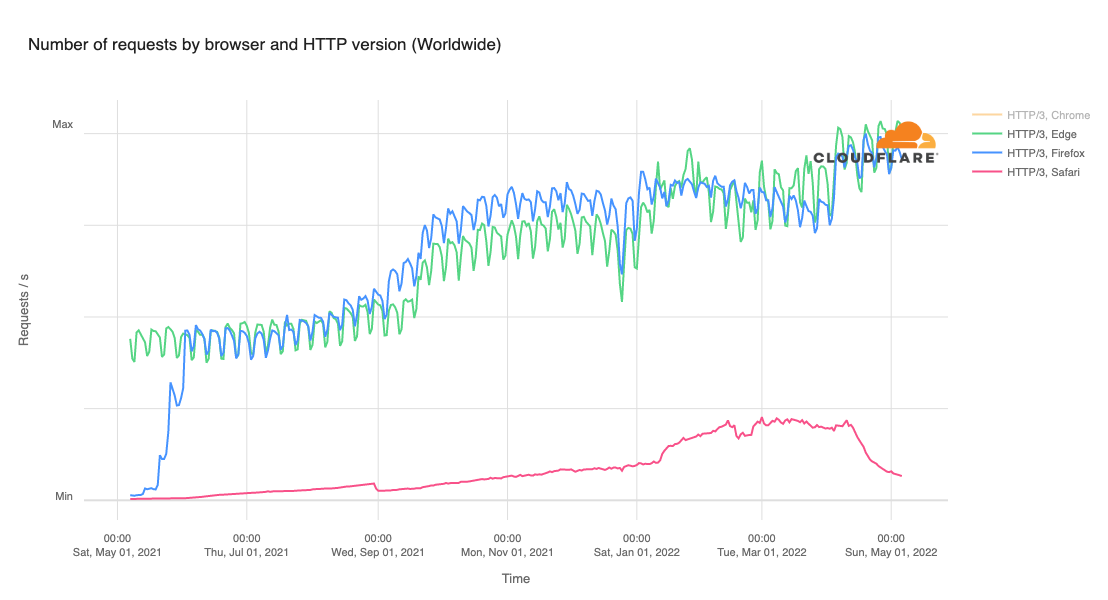
Looking at the lines in the graph for Chrome, Edge, and Firefox, a weekly cycle is clearly visible in the graph, suggesting greater usage of these browsers during the work week. This same pattern is absent from Safari usage.
Across the surveyed browsers, Chrome ultimately accounts for approximately 80% of the HTTP/3 requests seen by Cloudflare, as illustrated in the graphs below. Edge is responsible for around another 10%, with Firefox just under 10%, and Safari responsible for the balance.
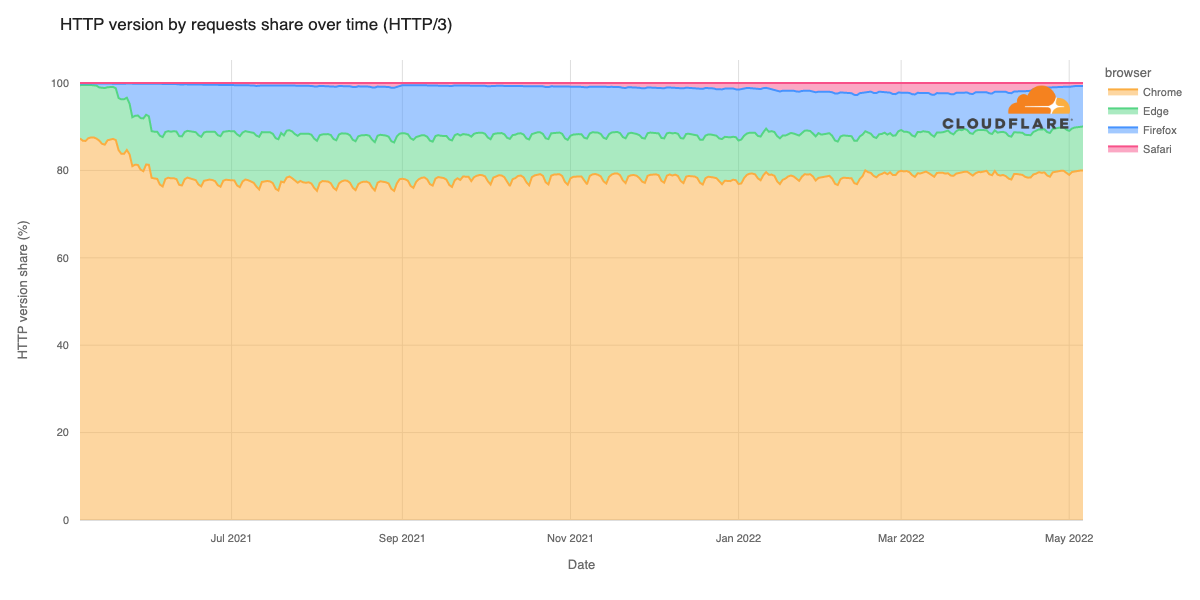
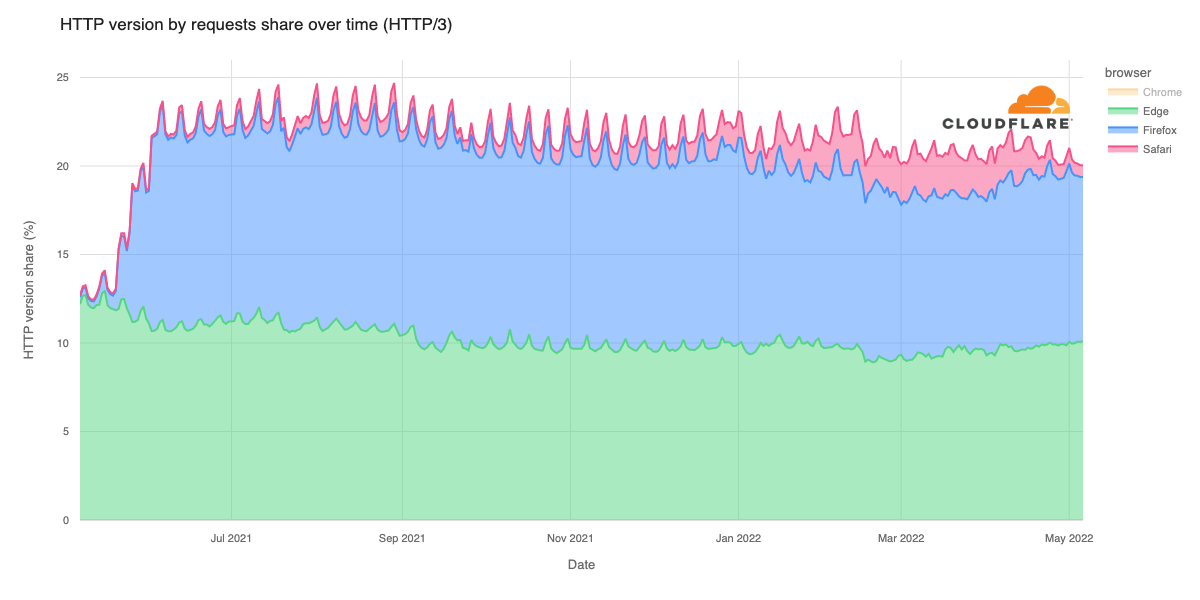
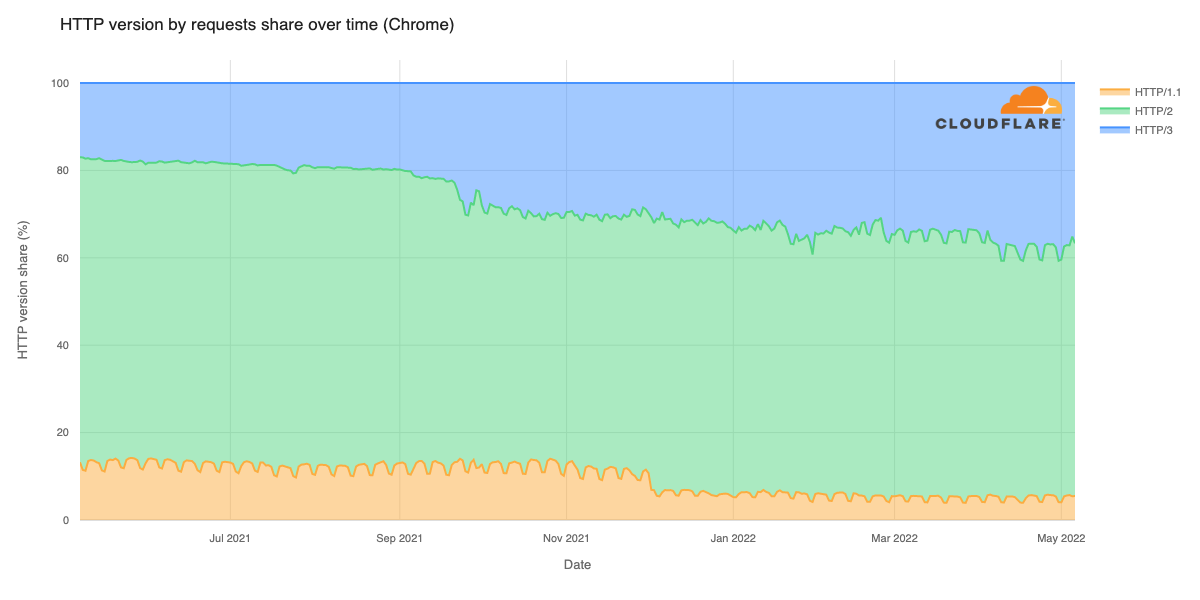
We also wanted to look at how the mix of HTTP versions has changed over the last year across each of the leading browsers. Although the percentages vary between browsers, it is interesting to note that the trends are very similar across Chrome, Firefox and Edge. (After Firefox turned on default HTTP/3 support in May 2021, of course.) These trends are largely customer-driven – that is, they are likely due to changes in Cloudflare customer configurations.
Most notably we see an increase in HTTP/3 during the last week of September, and a decrease in HTTP/1.1 at the beginning of December. For Safari, the HTTP/1.1 drop in December is also visible, but the HTTP/3 increase in September is not. We expect that over time, once Safari supports HTTP/3 by default that its trends will become more similar to those seen for the other browsers.
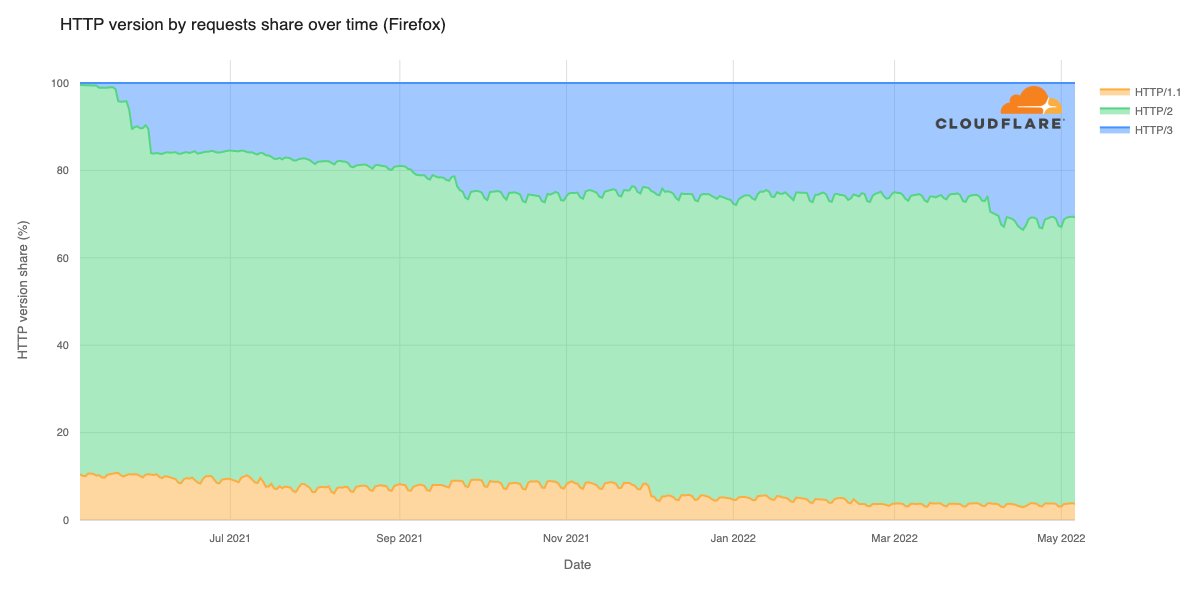
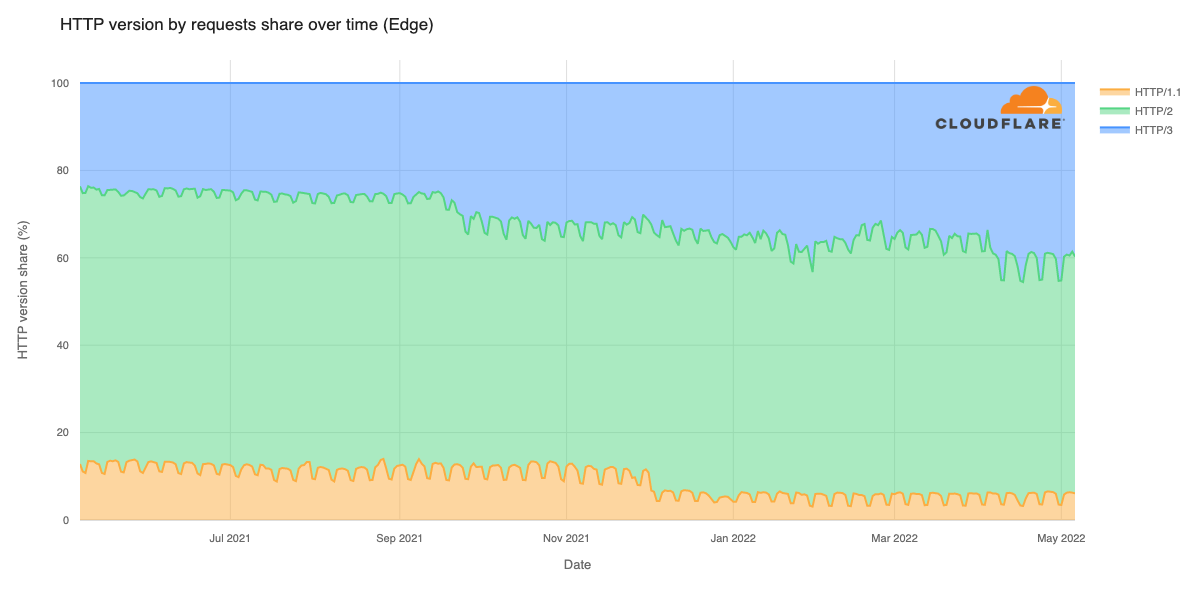
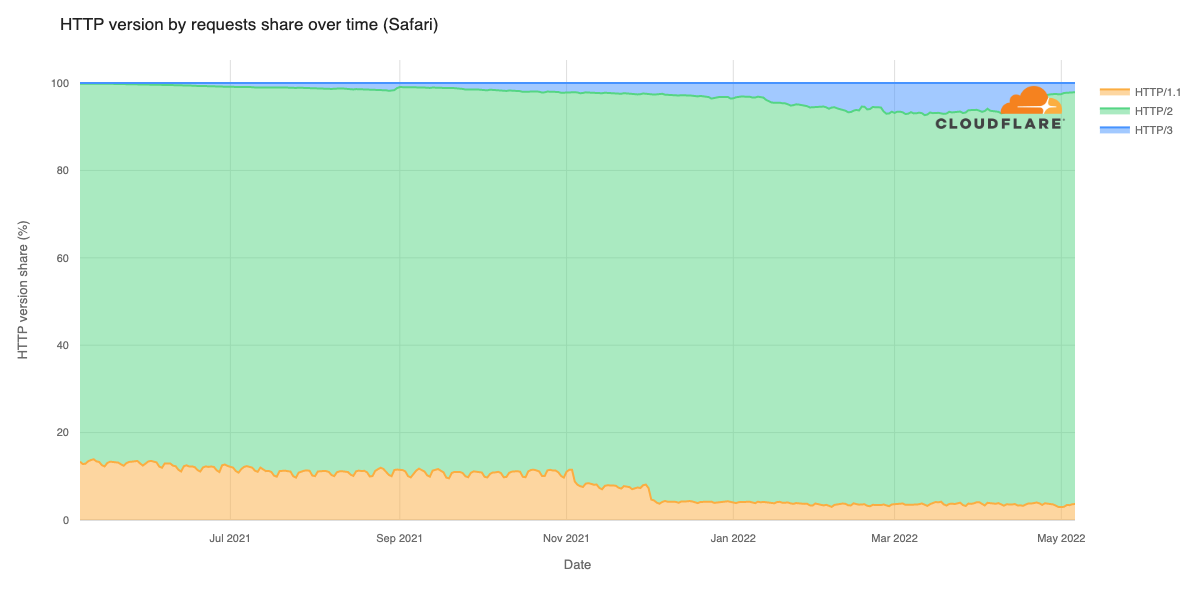
Back in 2014, Google announced that it would start to consider HTTPS usage as a ranking signal as it indexed websites. However, it does not appear that Google, or any of the other major search engines, currently consider support for the latest versions of HTTP as a ranking signal. (At least not directly – the performance improvements associated with newer versions of HTTP could theoretically influence rankings.) Given that, we wanted to understand which versions of HTTP the indexing bots themselves were using.
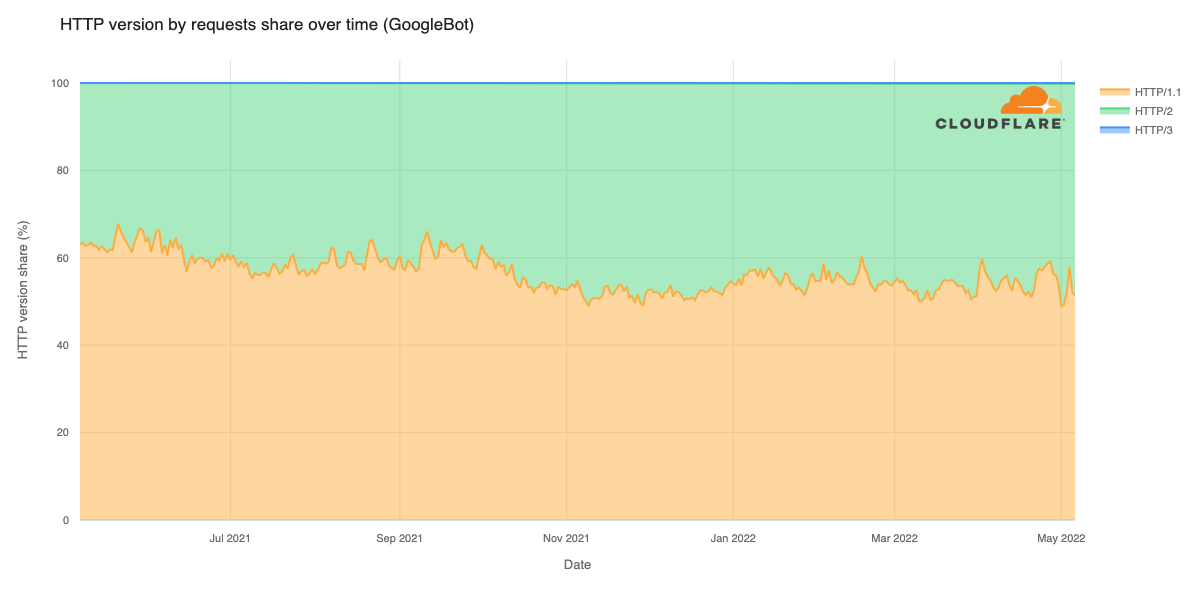
Despite leading the charge around the development of QUIC, and integrating HTTP/3 support into the Chrome browser early on, it appears that on the indexing/crawling side, Google still has quite a long way to go. The graph below shows that requests from GoogleBot are still predominantly being made over HTTP/1.1, although use of HTTP/2 has grown over the last six months, gradually approaching HTTP/1.1 request volume. (A blog post from Google provides some potential insights into this shift.) Unfortunately, the volume of requests from GoogleBot over HTTP/3 has remained extremely limited over the last year.
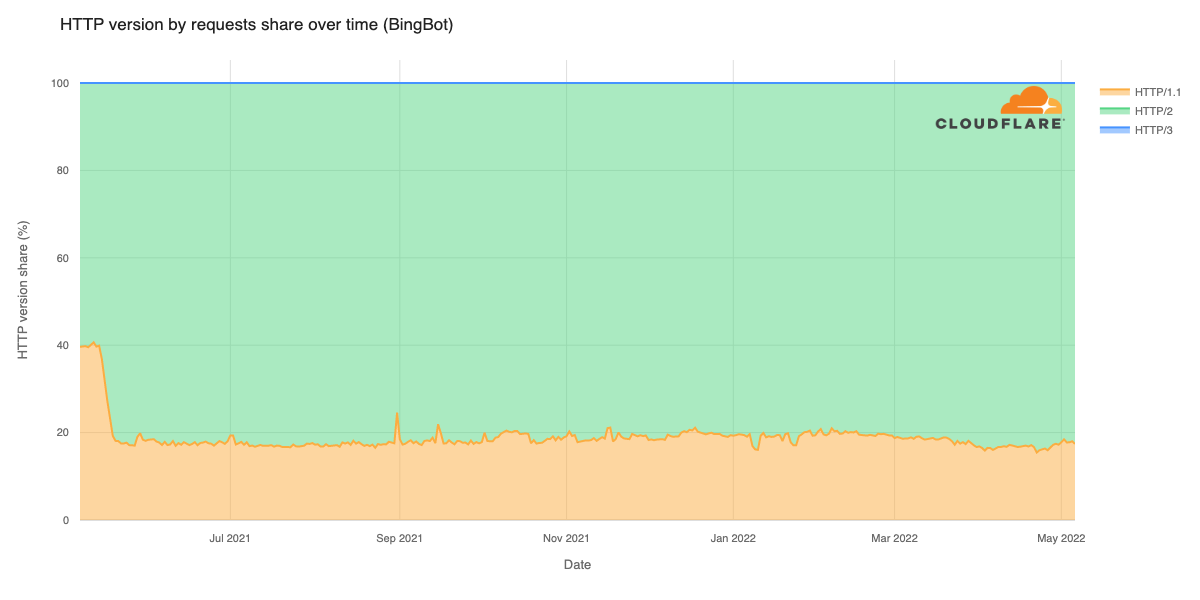
Microsoft’s BingBot also fails to use HTTP/3 when indexing sites, with near-zero request volume. However, in contrast to GoogleBot, BingBot prefers to use HTTP/2, with a wide margin developing in mid-May 2021 and remaining consistent across the rest of the past year.
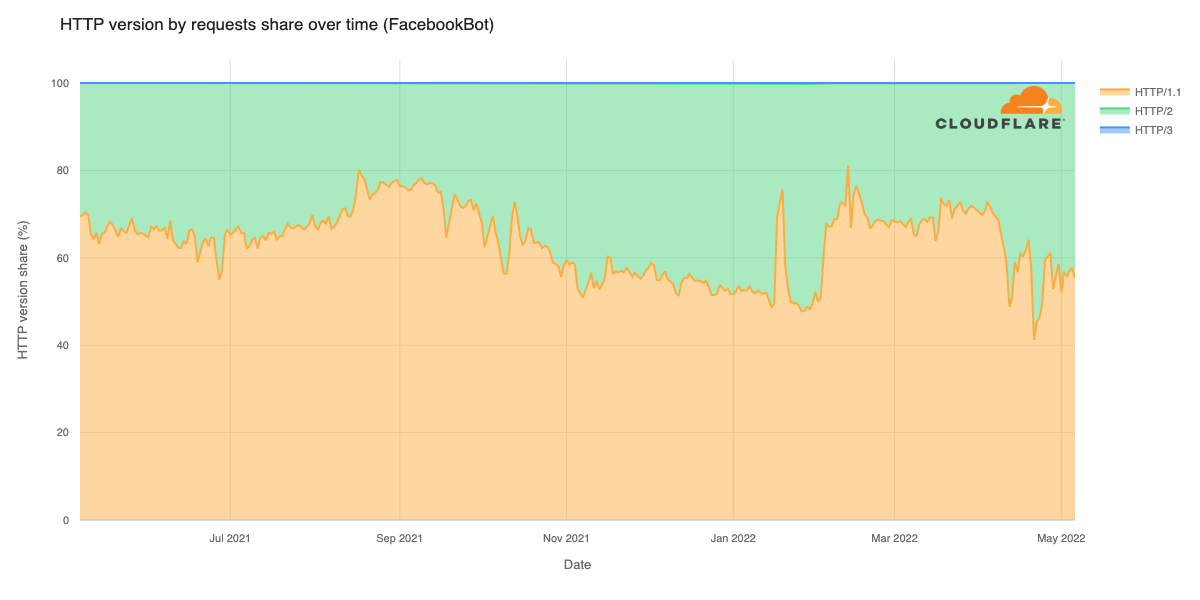
Major social media platforms use custom bots to retrieve metadata for shared content, improve language models for speech recognition technology, or otherwise index website content. We also surveyed the HTTP version preferences of the bots deployed by three of the leading social media platforms.
Although Facebook supports HTTP/3 on their main website (and presumably their mobile applications as well), their back-end FacebookBot crawler does not appear to support it. Over the last year, on the order of 60% of the requests from FacebookBot have been over HTTP/1.1, with the balance over HTTP/2. Heading into 2022, it appeared that HTTP/1.1 preference was trending lower, with request volume over the 25-year-old protocol dropping from near 80% to just under 50% during the fourth quarter. However, that trend was abruptly reversed, with HTTP/1.1 growing back to over 70% in early February. The reason for the reversal is unclear.
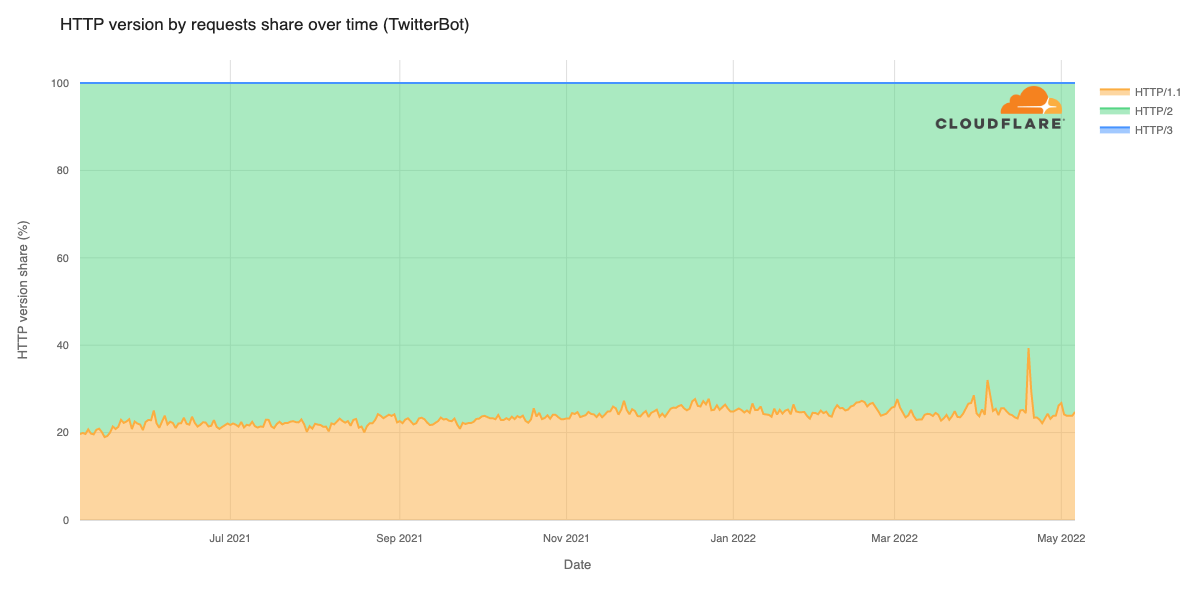
Similar to FacebookBot, it appears TwitterBot’s use of HTTP/3 is, unfortunately, pretty much non-existent. However, TwitterBot clearly has a strong and consistent preference for HTTP/2, accounting for 75-80% of its requests, with the balance over HTTP/1.1.
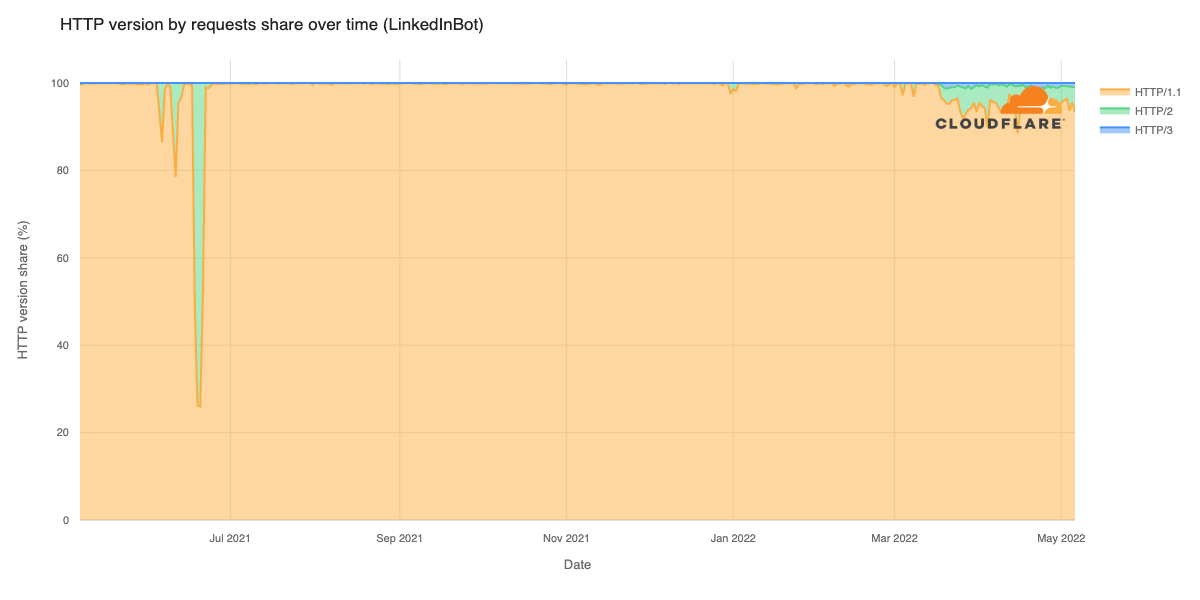
In contrast, LinkedInBot has, over the last year, been firmly committed to making requests over HTTP/1.1, aside from the apparently brief anomalous usage of HTTP/2 last June. However, in mid-March, it appeared to tentatively start exploring the use of other HTTP versions, with around 5% of requests now being made over HTTP/2, and around 1% over HTTP/3, as seen in the upper right corner of the graph below.
We’re happy that HTTP/3 has, at long last, been published as RFC 9114. More than that, we’re super pleased to see that regardless of the wait, browsers have steadily been enabling support for the protocol by default. This allows end users to seamlessly gain the advantages of HTTP/3 whenever it is available. On Cloudflare’s global network, we’ve seen continued growth in the share of traffic speaking HTTP/3, demonstrating continued interest from customers in enabling it for their sites and services. In contrast, we are disappointed to see bots from the major search and social platforms continuing to rely on aging versions of HTTP. We’d like to build a better understanding of how these platforms chose particular HTTP versions and welcome collaboration in exploring the advantages that HTTP/3, in particular, could provide.
Current statistics on HTTP/3 and QUIC adoption at a country and autonomous system (ASN) level can be found on Cloudflare Radar.
Running HTTP/3 and QUIC on the edge for everyone has allowed us to monitor a wide range of aspects related to interoperability and performance across the Internet. Stay tuned for future blog posts that explore some of the technical developments we’ve been making.
And this certainly isn’t the end of protocol innovation, as HTTP/3 and QUIC provide many exciting new opportunities. The IETF and wider community are already underway building new capabilities on top, such as MASQUE and WebTransport. Meanwhile, in the last year, the QUIC Working Group has adopted new work such as QUIC version 2, and the Multipath Extension to QUIC.
Post Syndicated from Omar Haq original https://aws.amazon.com/blogs/security/get-more-out-of-service-control-policies-in-a-multi-account-environment/
Many of our customers use AWS Organizations to manage multiple Amazon Web Services (AWS) accounts. There are many benefits to using multiple accounts in your organization, such as grouping workloads with a common business purpose, complying with regulatory frameworks, and establishing strong isolation barriers between applications based on ownership. Customers are even using distinct accounts for development, testing, and production. As these accounts proliferate, customers need a way to centrally set guardrails and controls.
In this blog post, we will walk you through different techniques that you can use to get more out of AWS Organizations service control policies (SCPs) in a multi-account environment. We focus on policy evaluation logic and how SCPs fit into it, show an overview of SCP inheritance, and describe methods for writing compact SCPs. We cover the following five techniques:
AWS Organizations provides a mechanism to set distinct logical boundaries by using organizational units (OUs). This is useful when you have similar workloads across different AWS accounts that require common guardrails. SCPs are a type of organization policy that you can use to manage permissions in your organization. SCPs offer central control over the maximum available permissions for all accounts in your organization. SCPs help you make sure that your accounts stay within your organization’s access control guidelines. A key distinction of SCPs is that they are useful to set broad guardrails across your environment. You can think of guardrails as a way to enforce specific governance policies at varying levels of your environment, which we will discuss in this post.
Before we dig into the details, let’s first look at how SCPs work from an overall policy perspective, along with the evaluation logic. An explicit Deny statement in any policy trumps an Allow statement. Organization SCPs that apply to any AWS account that is part of an organization in AWS Organizations require an Allow statement before proceeding in the policy evaluation flow.
For an in-depth look at how policies are evaluated, see Policy evaluation logic in the documentation.
Now, let’s walk through five recommended techniques that can help you get more out of SCPs.
An organization is a collection of AWS accounts that you manage together. You can use OUs to group accounts within an organization and administer them as a single unit. This greatly simplifies the management of your accounts. It’s possible to create multiple OUs within a single organization, and you can create OUs within other OUs, otherwise known as nested OUs. You have the flexibility to attach multiple policies to the root of the organization, to an OU, or to an account. For example, in an organization that has the root, one OU, and one account, attaching five SCPs to each of them would produce a total of 15 SCPs (five SCPs at the root, five SCPs at the OU, and five SCPs on the one account).
The number of SCPs that you can apply is limited, and being close to or at the quota could restrict your ability to add more policies in the future. The current published quotas are as follows:
Note: For the latest information on quotas, see Quotas for AWS Organizations.
Consider the following sample organization structure to understand how you can apply multiple SCPs at different levels in an organization.

Figure 1: A sample organization showing the maximum number of SCPs applicable at each level (root, OU, account)
Policy inheritance refers to the inheritance of policies that are attached to the organization’s root or to an OU. All accounts that are members of the organization root or OU where a policy is attached are affected by that policy, but inheritance works differently for Allow and Deny statements. For a permission to be allowed for a specified account, every SCP from the root through each OU in the direct path to the account, and even attached to the account itself, must allow that permission. In other words, a statement that allows access needs to exist at every level of a hierarchy; it’s not inherited. However, a Deny statement is inherited and evaluated at each level.
At this point, you should start thinking about the policies from a broader controls perspective: Controls that you want to implement on the whole organization should go into your organization’s root-level SCP. Controls should be more granular as you move down the hierarchy in AWS Organizations.
For example, when a Deny policy is attached to the organization’s root, all accounts in the organization are affected by that policy. When you attach a Deny policy to a specific OU, accounts that are directly under that OU or nested OUs under it are affected by that policy. Because you can attach policies to multiple levels in the organization, accounts might have multiple applicable policy documents, as shown in Figure 2.

Figure 2: Sample organization showing applicable policies
By default, AWS Organizations attaches an AWS managed SCP named FullAWSAccess to every root and OU when it’s created. This policy allows all services and actions.
Note: Adding an SCP with full AWS access doesn’t give all the principals in an account access to everything. SCPs don’t grant permissions; they are used to filter permissions. Principals still need a policy within the account that grants them access.
Additionally, the policies that are applied to an OU only affect the accounts or the child OUs under it and don’t affect other OUs created under the root. For example, a policy applied to the Sandbox OU doesn’t affect the Workloads OU.
The two tables that follow show examples of the policies that result from inheritance. As discussed previously, if an Allow isn’t present at all levels (root, OU, and account) the account won’t have access to any service. Consider the last example in the Sandbox OU table with a “Deny S3 access” SCP at the root, which limits access to Amazon Simple Storage Service (Amazon S3). Although there is “Allow S3 access” applied to the Sandbox OU and “Full AWS access” at the account level, the resultant policy on account A is “No service access” because there is no policy with an effect of “Allow” in the SCP at the root level.
The following table shows the inheritance of policies in the Sandbox OU.
| SCP at root | SCP at Sandbox OU | SCP at account A | Resultant policy at account A | Resultant policy at accounts B and C |
| Full AWS access | Full AWS access + deny S3 access | Full AWS access + deny EC2 access | No S3, no EC2 access | No S3 access |
| Full AWS access | Allow Amazon Elastic Compute Cloud (Amazon EC2) access | Allow EC2 access | Allows EC2 access only | Allows EC2 access only |
| Deny S3 access | Allow S3 access | Full AWS access | No service access | No service access |
The following table shows the inheritance of policies in the Workloads OU.
| SCP at root | SCP at Workloads OU | SCP at Test OU | Resultant policy at account D | Resultant policies at production OU/accounts E and F |
| Full AWS access | Full AWS access | Full AWS access + deny EC2 access | No EC2 access | Full AWS access |
| Full AWS access | Full AWS access | Allow EC2 access | Allows EC2 access | Full AWS access |
| Deny S3 access | Full AWS access | Allow S3 access | No service access | No service access |
Some examples of common root-level policies are as follows:
For sample SCPs, see Example service control policies. For insight into best practices for applying policies at different levels in an organization, see Best practices for SCPs in a multi-account environment.
A key feature of AWS Organizations is the ability to create distinct workload boundaries by using organizational units (OUs). You can think of OUs as a logical boundary where you can directly apply SCPs. You can also nest OUs up to five levels deep and apply different policies at each level. By using OUs, you can segment your workload types and create purpose-driven guardrails to match your security and compliance requirements.
To illustrate this, let’s take an example where there are three distinct workload types divided into three separate OUs: Infrastructure, Sandbox, and Workload, as shown in Figure 3. A best practice would be to tailor your SCPs to each specific OU type. Your security organization wouldn’t want to allow private workloads to be reachable from the internet. However, workloads that serve your external customers would require external network connectivity. To support innovation and experimentation, you can establish a Sandbox OU that has fewer policy restrictions but might limit connectivity back to your corporate data center.
For additional information on how to organize your OUs, see Recommended OUs.

Figure 3: Example organization showing different workloads
Similar to AWS Identity and Access Management (IAM) policies, you can have multiple statements within a service control policy. You can combine statements in a single policy to avoid hitting the quota limit of five policies per account, OU, or root. An AWS full access policy is attached by default when you enable SCPs on an organization. You can combine the full access policy with additional controls and combine statements, as shown in the following example policy. Each SCP that you apply can have a policy size of 5,120 bytes. When combining statements, make sure that the resultant statement doesn’t alter your original intent. You can combine the Action elements in an SCP if the policy has the same values for Effect, Resource, and Condition.
AWS full access policy (143 bytes)
You can combine this full access policy with the following deny policy:
Deny bucket deletion and Security Hub disablement (260 bytes)
The resulting combined policy is as follows:
Combined policy (274 bytes)
One difference between IAM policies and SCPs is that whitespace counts against the size quota in SCPs. Compacting related actions in a policy can help you shorten the policy. Following are four methods to compact your policy:
By using wildcards and prefixes, you can rewrite this policy as follows:
Important: When you combine actions together as in this example, be aware that there could be a potential impact if new actions are released in the future that start with the Disable keyword, because these actions will be covered by the wildcard and denied.
Consider the following scenario: Your security organization requires that application teams use specific AWS Regions. The recommended approach is to create a deny list that blocks everything except what is in the NotAction block. Following is an example where the SCP denies any operation outside of specified Regions that your organization has authorized for use.
Note: The list includes AWS global services that cannot be allowlisted based on a Region.
The following sample Python code can compress a provided policy by removing whitespace and Sid values.
You can export the compressed policy in the file named Compressed_Policy.json or show the output on the terminal by removing # from the following code.
Example output on screen:
To download the sample python code and the example policy shown above, download the files compress-policy.py and policy.json.
In this post, we walked you through different techniques that you can use to get more out of service control policies in a multi-account environment. By using these techniques, you can establish a well-considered strategy for how your organization can adopt SCPs in a multi-account environment. You also learned about how SCPs fit into the overall policy landscape for AWS. SCPs are a powerful tool to help customers establish guardrails. As you evaluate your IAM strategy, consider what you’re trying to achieve. If you’re trying to establish broad guardrails for multiple accounts, then we suggest looking at SCPs first.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Post Syndicated from Николай Марченко original https://bivol.bg/%D0%B7%D0%B0%D0%BC-%D0%BC%D0%B8%D0%BD%D0%B8%D1%81%D1%82%D1%8A%D1%80-%D0%B1%D1%80%D1%83%D1%82%D0%B0%D0%BB%D0%BD%D0%BE-%D0%B5-%D0%BD%D0%B0-%D0%BA%D0%B0%D0%BF%D0%B8%D1%82%D0%B0%D0%BD-%D0%B0%D0%BD%D0%B4.html

Признавам си, че ме е страх, но това в края на краищата не отслабва решимостта ми да си свърша работата. Това заяви в интервю за “Биволъ” ресорният зам.-министър на земеделието…
Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-week-in-review-june-6-2022/
I’ve just come back from a long (extended) holiday weekend here in the US and I’m still catching up on all the AWS launches that happened this past week. I’m particularly excited about some of the data, machine learning, and quantum computing news. Let’s have a look!
Last Week’s Launches
The launches that caught my attention last week are the following:
Amazon EMR Serverless is now generally available – Amazon EMR Serverless allows you to run big data applications using open-source frameworks such as Apache Spark and Apache Hive without configuring, managing, and scaling clusters. The new serverless deployment option for Amazon EMR automatically scales resources up and down to provide just the right amount of capacity for your application, and you only pay for what you use. To learn more, check out Channy’s blog post and listen to The Official AWS Podcast episode on EMR Serverless.
AWS PrivateLink is now supported by additional AWS services – AWS PrivateLink provides private connectivity between your virtual private cloud (VPC), AWS services, and your on-premises networks without exposing your traffic to the public internet. The following AWS services just added support for PrivateLink:
Amazon SageMaker JumpStart now supports incremental model training and automatic tuning – Besides ready-to-deploy solution templates for common machine learning (ML) use cases, SageMaker JumpStart also provides access to more than 300 pre-trained, open-source ML models. You can now incrementally train all the JumpStart models with new data without training from scratch. Through this fine-tuning process, you can shorten the training time to reach a better model. SageMaker JumpStart now also supports model tuning with SageMaker Automatic Model Tuning from its pre-trained model, solution templates, and example notebooks. Automatic tuning allows you to automatically search for the best hyperparameter configuration for your model.
Amazon Transcribe now supports automatic language identification for multi-lingual audio – Amazon Transcribe converts audio input into text using automatic speech recognition (ASR) technology. If your audio recording contains more than one language, you can now enable multi-language identification, which identifies all languages spoken in the audio file and creates a transcript using each identified language. Automatic language identification for multilingual audio is supported for all 37 languages that are currently supported for batch transcriptions. Read the What’s New post from Amazon Transcribe to learn more.
Amazon Braket adds support for Borealis, the first publicly accessible quantum computer that is claimed to offer quantum advantage – If you are interested in quantum computing, you’ve likely heard the term “quantum advantage.” It refers to the technical milestone when a quantum computer outperforms the world’s fastest supercomputers on a well-defined task. Until now, none of the devices claimed to demonstrate quantum advantage have been accessible to the public. The Borealis device, a new photonic quantum processing unit (QPU) from Xanadu, is the first publicly available quantum computer that is claimed to have achieved quantum advantage. Amazon Braket, the quantum computing service from AWS, has just added support for Borealis. To learn more about how you can test a quantum advantage claim for yourself now on Amazon Braket, check out the What’s New post covering the addition of Borealis support.
For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.
Other AWS News
Some other updates and news that you may have missed:
New AWS Heroes – A warm welcome to our newest AWS Heroes! The AWS Heroes program is a worldwide initiative that acknowledges individuals who have truly gone above and beyond to share knowledge in technical communities. Get to know them in the June 2022 introduction blog post!
AWS open-source news and updates – My colleague Ricardo Sueiras writes this weekly open-source newsletter in which he highlights new open-source projects, tools, and demos from the AWS Community. Read edition #115 here.
Upcoming AWS Events
 Join me in Las Vegas for Amazon re:MARS 2022. The conference takes place June 21–24 and is all about the latest innovations in machine learning, automation, robotics, and space. I will deliver a talk on how machine learning can help to improve disaster response. Say “Hi!” if you happen to be around and see me.
 We also have more AWS Summits coming up over the next couple of months, both in-person and virtual.
In Europe:
In North America:
In South America:
Find an AWS Summit near you, and get notified when registration opens in your area.
 You can now register for IMAGINE 2022 (August 3, Seattle). The IMAGINE 2022 conference is a no-cost event that brings together education, state, and local leaders to learn about the latest innovations and best practices in the cloud.
Sign up for the SQL Server Database Modernization webinar on June 21 to learn how to modernize and cost-optimize Microsoft SQL Server on AWS.
That’s all for this week. Check back next Monday for another Week in Review!
— Antje
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/scaling-appsec-at-netflix-part-2-c9e0f1488bc5
By Astha Singhal, Lakshmi Sudheer, Julia Knecht
The Application Security teams at Netflix are responsible for securing the software footprint that we create to run the Netflix product, the Netflix studio, and the business. Our customers are product and engineering teams at Netflix that build these software services and platforms. The Netflix cultural values of ‘Context not Control’ and ‘Freedom and Responsibility’ strongly influence how we do Security at Netflix. Our goal is to manage security risks to Netflix via clear, opinionated security guidance, and by providing risk context to Netflix engineering teams to make pragmatic risk decisions at scale.
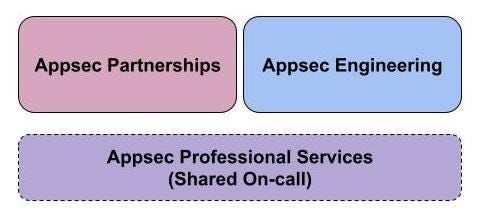
A few years ago, we published this blog post about how we had organized our team to focus our bandwidth on scalable investments as opposed to just traditional Appsec functions, which were not scaling well in our rapidly growing environment. We leaned into the idea of strategic security partnerships and automation investments to create more leverage for application security. This became the foundation for our current org structure with teams focused on Appsec Partnerships and Appsec Engineering. In this operating model, we provided critical Appsec operational services to Netflix — including bug bounty, pentesting, PSIRT (product security incident response), security reviews, and developer security education — via a shared on-call rotation.
Over the past few years, this model has allowed us to focus on investments like Secure by Default for baseline security controls, Security Self-Service for clear actionable guidance and Vulnerability Scanning at scale for software supply chain security. We wanted to share an update on learnings from this model, how our needs have evolved, and where we expect to go from here.
Among the most notable wins, we have been able to utilize this scale focused approach to productize application security for our rapidly growing studio engineering ecosystem, standardize security baseline for all Enterprise apps, and build paved roads to provide Secure by Default Authentication & Authorization capabilities for central data engineering tools. Our focus has been on improving overall security assurance as opposed to just vulnerability prevention. We are now expanding this approach to more parts of our ecosystem. This mindset has also allowed us to invest our capacity for white-glove service towards reasonable residual risk and standard guidance so we can reduce the need for white-glove engagements in the long term (e.g., investment in an API proxy that provides baseline security controls for free as opposed to pentesting all applications that would eventually sit behind that API proxy). This approach has also allowed us to build strong relationships with central engineering teams at Netflix (Data Platform, Developer Tools, Cloud Infrastructure, IAM Product Engineering) that will continue to serve as central points of leverage for security in the long term.
However, it has not been all sunshine and rainbows. On the partnership side, the bespoke nature of each partnership means that there isn’t consistency and redundancy built into the operating model and the related partnership artifacts (e.g., Security Strategy and Roadmap, Threat Model, Deliverable Tracking, Residual Risk Criteria, etc). This leads to insufficient context sharing and high operational churn every time we have personnel changes. The partnership charter has also grown laterally into the infrastructure space as we stack our leverage bets on infrastructure components (like Service Mesh, Container Platform, etc). The skill sets and domain depth in those partnerships has further diversified the skills on the team. But this is a tradeoff on our ability to serve generalized Appsec oncall needs like bug bounty triage with high consistency. Given that partnerships focus on long-running strategic initiatives, the wins can be few and far between and that can be difficult for team motivation. We also found various areas in which security partnership work bleeds into security product solutioning and it can be difficult to identify the appropriate handoff points.
Additionally, as the complexity of our ecosystem grows, the goal of “single PoC into information security” becomes increasingly more difficult to maintain. The team is now investing in consistency and scalability of partnership artifacts and communication channels, better redundancy and context sharing on the team through squad operating models, crisper engagement criteria, and definition of done for partnership engagements.
Our Appsec Engineering team builds products to help us scale, e.g.: a dynamic Asset Inventory that understands the nuances of our bespoke engineering ecosystem and how our applications and data relate to each other. This has evolved their identity to be a software engineering team that focuses on security problems as opposed to a security engineering team that writes code/software. Our hiring has reflected that shift, and we’ve added more dedicated software engineers (SWEs) to the team to help us build out software. With this shift, we’ve incorporated engineering best practices, and our products have appropriate investments toward reliability and sustainability. As the team skews towards more software engineering focused talent, ramping up to support the shared Appsec-focused on-call has been challenging.
While originally built to support AppSec use cases around providing guidance to developers in a self-service way, interest in the rich data and relationships we have in our tools, especially our Asset Inventory, has grown. As a result, we’ve continued to invest in making our solutions scalable and accessible, so security engineers can get the data they need more easily to drive security use cases. We’ve also discovered, through interviews with engineers, that self-service guidance doesn’t stand on its own. Moving forward, the team is investing in understanding our customer use cases better, and shifting our self-service story toward higher-context, more opinionated automated guidance to ensure developers have everything they need to make truly informed decisions about the security of their applications (similar to how they might make resiliency or other product decisions).
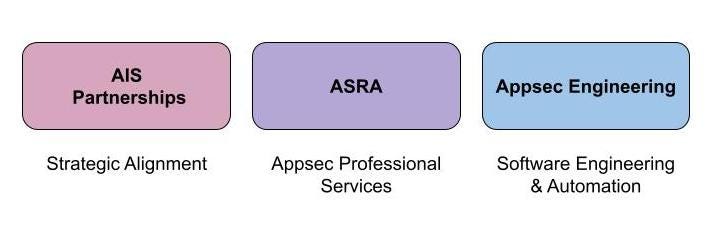
As the Netflix business and engineering workforce has grown, our software footprint has also grown and become more heterogeneous. At the same time, partnerships have grown more and more strategic, and engineering has grown more and more software-focused. As our team specialized, what emerged was a loss of strategic focus for our AppSec Professional Services charter. These services now need more dedicated strategic investment as the volume and support needs have grown. So, we are now building out a dedicated capability focused on these critical services that are important investments to be made and can no longer be served effectively via a shared Appsec on-call. This will be our “Appsec Reviews and Assessments” function and we are hiring for passionate, early career Appsec engineers to join this group.
We will continue to learn as we go through this next phase of evolution of our program. We hope to continue to share these learnings with the broader community interested in scalable product and application security.

Scaling Appsec at Netflix (Part 2) was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Post Syndicated from Thomas Attree original https://aws.amazon.com/blogs/architecture/use-templated-answers-to-perform-well-architected-reviews-at-scale/
For larger customers, performing AWS Well-Architected (AWS WA) Framework reviews often involves a combination of different teams. Coordinating participants from each team in order to perform a review increases the time taken and is expensive. In a large organization, there are often hundreds of AWS accounts where teams can store review documents, which means there is no way to quickly identify risks or spot common issues or trends that could influence improvements.
To address this, we created a solution to help you perform reviews easier and faster. It allows workload owners to automatically populate their reviews with templated answers to questions in the AWS Well-Architected Tool (AWS WA Tool). These answers may be a shared responsibility between an application team and a centralized team such as platform, security, or finance. This way, application teams have fewer questions to answer and centralized team members have fewer reviews to attend, because answers that are common to all workloads are pre-populated in workload reviews. The solution also provides centralized reporting to provide a centralized view of AWS WA reviews conducted across the organization.
In large organizations, responsibilities are often distributed across multiple teams, for example:
To perform a traditional AWS WA review for this example, you would likely need to invite representatives from each of these teams to attend the review. This is because one team would be unlikely to be able to answer the foundational questions alone.
With tens or hundreds of workloads being reviewed every year, this approach doesn’t scale. This is because representatives from central teams end up attending every review. With more people involved, scheduling reviews is difficult, the overall time required to conduct the review increases, and longer reviews with more people are more expensive to perform.
Additionally, the review document is usually created and stored in one of the application team’s AWS accounts. In a large organization, there are often hundreds of AWS accounts. This makes it difficult for leadership to get a consolidated view of the risks identified across the reviews. It also makes it almost impossible to spot common issues or trends that could influence roadmaps for organization-wide improvements.
Our solution allows you to address these challenges by using the AWS WA Tool to create answer templates. An answer template looks like a regular AWS WA Tool workload review. However, these answers propagate automatically to application workload reviews and are visible by application workload owners during the review process. This way, where there is a shared responsibility, workload owners can see this detail and they can be confident that the inputs provided by the central teams are correct and consistent.
The solution operates as shown in Figure 1 and works as follows:
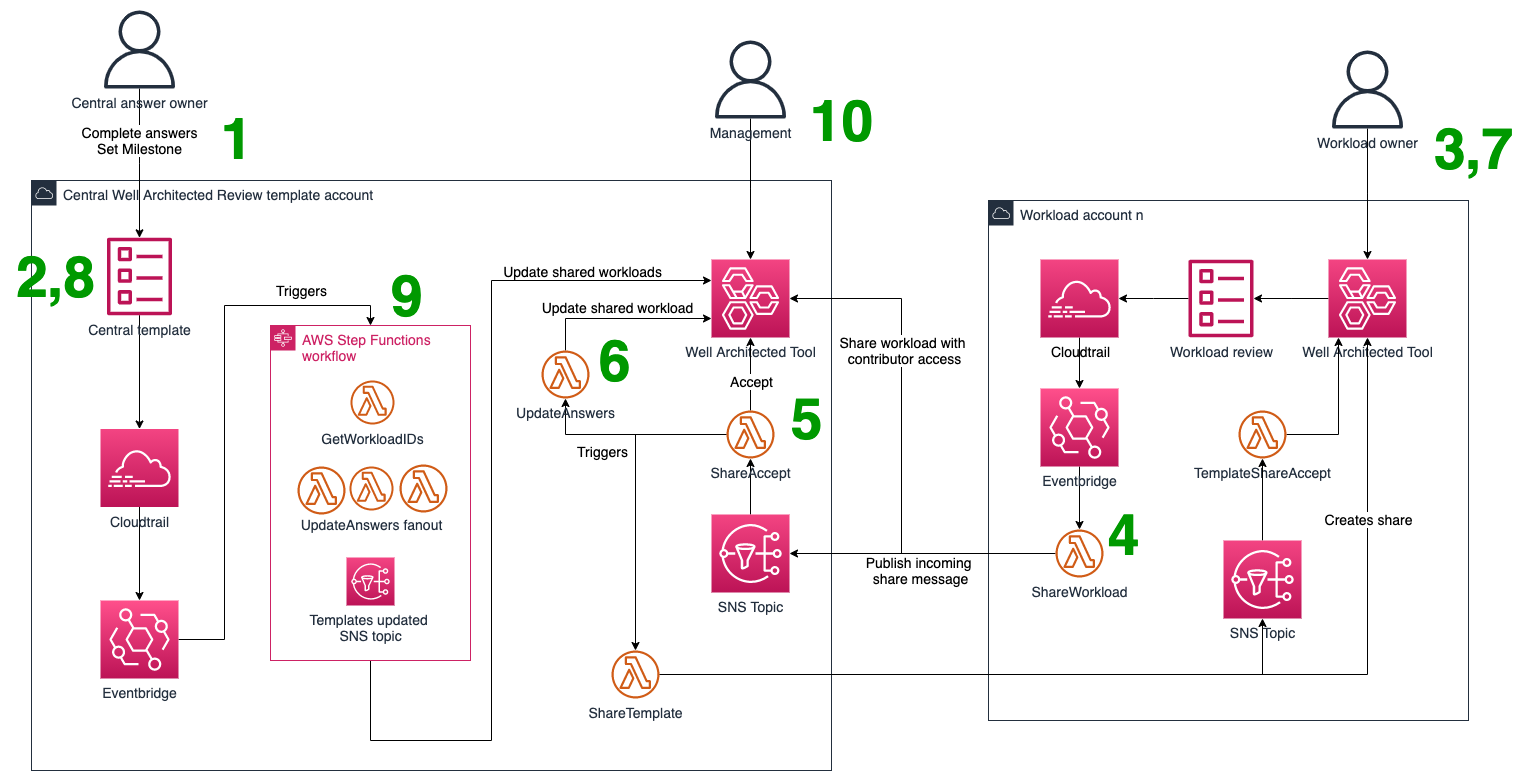
Figure 1. Solution components and workflow steps
The solution can be coupled with an Amazon QuickSight powered reporting solution to get an organization-wide view of reviews from a single account. These reviews can also be shared with your AWS account team for ongoing collaborative improvement.
Note: For some workloads, you may need additional AWS WA Framework lenses. The solution offered in this post is lens agnostic, and also supports the use of custom lenses. To deploy the solution, refer to the deployment instructions which can be found on GitHub under aws-samples.
In this post, we explored some of the challenges faced by large enterprises when performing AWS WA Framework reviews at scale and showed you a solution to help your teams define templated answers to particular questions in the AWS WA Tool.
You can deploy this solution to your AWS accounts today by following the deployment instructions included on the aws-samples repository.
Having these templated answers automatically propagated to application workload reviews reduces the number of questions application teams have to answer, as well as the number of attendees required for a review. With this solution, all the AWS WA Framework reviews can be viewed in a single AWS account, so you can also apply the reporting solution provided in AWS WA labs to run centralized reports against all AWS WA Framework reviews in your organization.
AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!
Post Syndicated from original https://lwn.net/Articles/897193/
Alyssa Rosenzweig announces
a milestone for support of Mali GPUs with free software:
The open source Panfrost driver for Mali GPUs now supports the new
Valhall architecture with fully-conformant OpenGL ES 3.1 on
Mali-G57, a Valhall GPU. The final Mesa patches are landing today,
and the required kernel patches are queued for merge upstream.
Post Syndicated from original https://lwn.net/Articles/896410/
The 5.19 merge window was closed with the 5.19-rc1
release on June 5 after the addition of 13,124 non-merge changesets
to the mainline
kernel. That makes this merge window another busy one, essentially
matching the 13,204 changesets seen for 5.18. The approximately 8,500
changesets merged since our first 5.19
merge-window summary contain quite a bit of new functionality; read on
for a summary of the most interesting changes that were pulled during the
second half of this merge window.
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=Qod8Rfjdh_E
Post Syndicated from Tod Beardsley original https://blog.rapid7.com/2022/06/06/the-hidden-harm-of-silent-patches/
Hey all. I’m about to head off to RSAC 2022, but I wanted to jot down some thoughts I’ve had lately on a particularly squirrelly issue that comes up occasionally in coordinated vulnerability disclosure (CVD) — the issue of silent patches, and how they tend to help focused attackers and harm IT protectors.
In the bad old days, most major software vendors were rather notorious for sweeping vulnerability reports under the rug. They made it difficult for legitimate researchers to report vulnerabilities, often by accident, occasionally on purpose. Researchers would report bugs, and those reports would fester in unobserved space, then suddenly the proof-of-concept exploit wouldn’t work any more. This was (and is) the standard silent patching model. No credit, no explanation, no CVE ID, nothing.
The justification for this approach seems pretty sensible, though. Why would a vendor go out of their way to explain what a security fix does? After all, if you know how the patch works, then you have a pretty good guess at the root cause of the vulnerability and, therefore, how the exploit works. So, by publicizing these patch details, you’re effectively leading attackers to the goods, based on your own documentation. Not cool, right?
So, the natural conclusion is that by limiting the technical details of a given vulnerability to merely the patch contents, and by withholding those details explained in plan languages and proof-of-concept exploit code and screenshots and videos and all the rest, you are limiting the general knowledge pool of people who actually understand the vulnerability and how to exploit it.
This sounds like a great plan, but there’s a catch. When a software company releases a patch for software, in nearly all cases, they’re not using exotic packers, they’re not employing anti-forensics, and even if the patch data is encrypted and obfuscated, at some point it’s got to modify the code on the running software — which means that it’s all available to anyone who has a running instance of the patched software and knows how to use a debugger and a disassembler. And who uses debuggers to inspect the effects of patches? Exploit developers, pretty much exclusively.
Knowing this, let’s modify the expectations of the silent patch strategy: When you silently patch, you are intending to limit knowledge of the patched vulnerability to skilled exploit devs.
It’s still true that you’re excluding the casual attacker (or “script kiddie,” in the common parlance), and that’s great and desirable. However, you’re also excluding a huge population of IT protectors: penetration testers who are paid to write and run exploits to test defenses leap to mind, in addition to the folks who write and deploy defensive technologies like vulnerability management, intrusion detection and prevention, incident detection, and all the rest. You also exclude tech journalists, academics, and policy makers who want to understand and communicate the nature of software vulnerabilities, but who aren’t likely to bust out a disassembler.
Most significantly, you’re excluding the most important audience for your patch: the regular IT administrators and managers who need to sort out the incoming flow of patches based on some risk and severity criteria and make the call for downtime and update scheduling based on that criteria. Not all vulnerabilities are equal, and while protectors want to get around to all of them, they need to figure out which ones to apply today and which ones can wait for the next maintenance cycle.
By the way, it’s true that some of these IT professionals also have the capability to reverse-engineer your patch. In practice, people who are only interested in keeping IT humming never, ever reverse patches to see if they’re worth applying. It’s way too complicated and time-consuming. I’ve never seen a case where this is part of the decision-making process to patch now or later.
So now, let’s reexamine the case for silent patching yet again: When you silently patch, you are communicating vulnerability details, exclusively, to skilled, criminal attackers who are specifically targeting your product, while leaving your customers in the dark. You are intentionally withholding information from casual attackers, secondary defenders, and your customers and users who are desperate to make informed security engineering decisions involving your product or project. Oh, and let’s not forget, you’re also limiting knowledge about these fixed vulnerabilities from future employees and contributors, who very well might re-introduce the same or similar bugs in your product down the road. After all, the details are secret, even from future-you.
All this is to say, silent patching is tantamount to full disclosure to a very small audience who mostly want to hurt you and your users. Fully documented patches reach the much, much larger audience of people, present and future, who want to help you and your users. While it’s true that you are also offering educational opportunities to casual attackers along the way, I believe the global population of casual attackers is much, much smaller than your legitimate users and all the secondary and tertiary defenders who are on your side.
So, next time a vulnerability researcher states their intention of publishing details about their reported (and now patched) vulnerability, try to examine your urge to keep those details under wraps, and maybe even encourage them to be honest and transparent with their findings. The alternative is to build up the operational capabilities of the true criminal and espionage enterprises while degrading the decision-making power of IT protectors.
Additional reading:
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/06/long-story-on-the-accused-cia-vault-7-leaker.html
Long article about Joshua Schulte, the accused leaker of the WikiLeaks Vault 7 and Vault 8 CIA data.
Well worth reading.
Post Syndicated from Marta Taggart original https://aws.amazon.com/blogs/security/a-sneak-peek-at-the-data-protection-and-privacy-sessions-for-reinforce-2022/
Register now with discount code SALUZwmdkJJ to get $150 off your full conference pass to AWS re:Inforce. For a limited time only and while supplies last.
Today we want to tell you about some of the engaging data protection and privacy sessions planned for AWS re:Inforce. AWS re:Inforce is a learning conference where you can learn more about on security, compliance, identity, and privacy. When you attend the event, you have access to hundreds of technical and business sessions, an AWS Partner expo hall, a keynote speech from AWS Security leaders, and more. AWS re:Inforce 2022 will take place in-person in Boston, MA on July 26 and 27. re:Inforce 2022 features content in the following five areas:
This post will highlight of some of the data protection and privacy offerings that you can sign up for, including breakout sessions, chalk talks, builders’ sessions, and workshops. For the full catalog of all tracks, see the AWS re:Inforce session preview.
Lecture-style presentations that cover topics at all levels and delivered by AWS experts, builders, customers, and partners. Breakout sessions typically include 10–15 minutes of Q&A at the end.
DPP 101: Building privacy compliance on AWS
In this session, learn where technology meets governance with an emphasis on building. With the privacy regulation landscape continuously changing, organizations need innovative technical solutions to help solve privacy compliance challenges. This session covers three unique customer use cases and explores privacy management, technology maturity, and how AWS services can address specific concerns. The studies presented help identify where you are in the privacy journey, provide actions you can take, and illustrate ways you can work towards privacy compliance optimization on AWS.
DPP201: Meta’s secure-by-design approach to supporting AWS applications
Meta manages a globally distributed data center infrastructure with a growing number of AWS Cloud applications. With all applications, Meta starts by understanding data security and privacy requirements alongside application use cases. This session covers the secure-by-design approach for AWS applications that helps Meta put automated safeguards before deploying applications. Learn how Meta handles account lifecycle management through provisioning, maintaining, and closing accounts. The session also details Meta’s global monitoring and alerting systems that use AWS technologies such as Amazon GuardDuty, AWS Config, and Amazon Macie to provide monitoring, access-anomaly detection, and vulnerable-configuration detection.
DPP202: Uplifting AWS service API data protection to TLS 1.2+
AWS is constantly raising the bar to ensure customers use the most modern Transport Layer Security (TLS) encryption protocols, which meet regulatory and security standards. In this session, learn how AWS can help you easily identify if you have any applications using older TLS versions. Hear tips and best practices for using AWS CloudTrail Lake to detect the use of outdated TLS protocols, and learn how to update your applications to use only modern versions. Get guidance, including a demo, on building metrics and alarms to help monitor TLS use.
DPP203: Secure code and data in use with AWS confidential compute capabilities
At AWS, confidential computing is defined as the use of specialized hardware and associated firmware to protect in-use customer code and data from unauthorized access. In this session, dive into the hardware- and software-based solutions AWS delivers to provide a secure environment for customer organizations. With confidential compute capabilities such as the AWS Nitro System, AWS Nitro Enclaves, and NitroTPM, AWS offers protection for customer code and sensitive data such as personally identifiable information, intellectual property, and financial and healthcare data. Securing data allows for use cases such as multi-party computation, blockchain, machine learning, cryptocurrency, secure wallet applications, and banking transactions.
Small-group sessions led by an AWS expert who guides you as you build the service or product on your own laptop. Use your laptop to experiment and build along with the AWS expert.
DPP251: Disaster recovery and resiliency for AWS data protection services
Mitigating unknown risks means planning for any situation. To help achieve this, you must architect for resiliency. Disaster recovery (DR) is an important part of your resiliency strategy and concerns how your workload responds when a disaster strikes. To this end, many organizations are adopting architectures that function across multiple AWS Regions as a DR strategy. In this builders’ session, learn how to implement resiliency with AWS data protection services. Attend this session to gain hands-on experience with the implementation of multi-Region architectures for critical AWS security services.
DPP351: Implement advanced access control mechanisms using AWS KMS
Join this builders’ session to learn how to implement access control mechanisms in AWS Key Management Service (AWS KMS) and enforce fine-grained permissions on sensitive data and resources at scale. Define AWS KMS key policies, use attribute-based access control (ABAC), and discover advanced techniques such as grants and encryption context to solve challenges in real-world use cases. This builders’ session is aimed at security engineers, security architects, and anyone responsible for implementing security controls such as segregating duties between encryption key owners, users, and AWS services or delegating access to different principals using different policies.
DPP352: TLS offload and containerized applications with AWS CloudHSM
With AWS CloudHSM, you can manage your own encryption keys using FIPS 140-2 Level 3 validated HSMs. This builders’ session covers two common scenarios for CloudHSM: TLS offload using NGINX and OpenSSL Dynamic agent and a containerized application that uses PKCS#11 to perform crypto operations. Learn about scaling containerized applications, discover how metrics and logging can help you improve the observability of your CloudHSM-based applications, and review audit records that you can use to assess compliance requirements.
DPP353: How to implement hybrid public key infrastructure (PKI) on AWS
As organizations migrate workloads to AWS, they may be running a combination of on-premises and cloud infrastructure. When certificates are issued to this infrastructure, having a common root of trust to the certificate hierarchy allows for consistency and interoperability of the public key infrastructure (PKI) solution. In this builders’ session, learn how to deploy a PKI that allows such capabilities in a hybrid environment. This solution uses Windows Certificate Authority (CA) and ACM Private CA to distribute and manage x.509 certificates for Active Directory users, domain controllers, network components, mobile, and AWS services, including Amazon API Gateway, Amazon CloudFront, and Elastic Load Balancing.
Highly interactive sessions with a small audience. Experts lead you through problems and solutions on a digital whiteboard as the discussion unfolds.
DPP231: Protecting healthcare data on AWS
Achieving strong privacy protection through technology is key to protecting patient. Privacy protection is fundamental for healthcare compliance and is an ongoing process that demands legal, regulatory, and professional standards are continually met. In this chalk talk, learn about data protection, privacy, and how AWS maintains a standards-based risk management program so that the HIPAA-eligible services can specifically support HIPAA administrative, technical, and physical safeguards. Also consider how organizations can use these services to protect healthcare data on AWS in accordance with the shared responsibility model.
DPP232: Protecting business-critical data with AWS migration and storage services
Business-critical applications that were once considered too sensitive to move off premises are now moving to the cloud with an extension of the security perimeter. Join this chalk talk to learn about securely shifting these mature applications to cloud services with the AWS Transfer Family and helping to secure data in Amazon Elastic File System (Amazon EFS), Amazon FSx, and Amazon Elastic Block Storage (Amazon EBS). Also learn about tools for ongoing protection as part of the shared responsibility model.
DPP331: Best practices for cutting AWS KMS costs using Amazon S3 bucket keys
Learn how AWS customers are using Amazon S3 bucket keys to cut their AWS Key Management Service (AWS KMS) request costs by up to 99 percent. In this chalk talk, hear about the best practices for exploring your AWS KMS costs, identifying suitable buckets to enable bucket keys, and providing mechanisms to apply bucket key benefits to existing objects.
DPP332: How to securely enable third-party access
In this chalk talk, learn about ways you can securely enable third-party access to your AWS account. Learn why you should consider using services such as Amazon GuardDuty, AWS Security Hub, AWS Config, and others to improve auditing, alerting, and access control mechanisms. Hardening an account before permitting external access can help reduce security risk and improve the governance of your resources.
Interactive learning sessions where you work in small teams to solve problems using AWS Cloud security services. Come prepared with your laptop and a willingness to learn!
DPP271: Isolating and processing sensitive data with AWS Nitro Enclaves
Join this hands-on workshop to learn how to isolate highly sensitive data from your own users, applications, and third-party libraries on your Amazon EC2 instances using AWS Nitro Enclaves. Explore Nitro Enclaves, discuss common use cases, and build and run an enclave. This workshop covers enclave isolation, cryptographic attestation, enclave image files, building a local vsock communication channel, debugging common scenarios, and the enclave lifecycle.
DPP272: Data discovery and classification with Amazon Macie
This workshop familiarizes you with Amazon Macie and how to scan and classify data in your Amazon S3 buckets. Work with Macie (data classification) and AWS Security Hub (centralized security view) to view and understand how data in your environment is stored and to understand any changes in Amazon S3 bucket policies that may negatively affect your security posture. Learn how to create a custom data identifier, plus how to create and scope data discovery and classification jobs in Macie.
DPP273: Architecting for privacy on AWS
In this workshop, follow a regulatory-agnostic approach to build and configure privacy-preserving architectural patterns on AWS including user consent management, data minimization, and cross-border data flows. Explore various services and tools for preserving privacy and protecting data.
DPP371: Building and operating a certificate authority on AWS
In this workshop, learn how to securely set up a complete CA hierarchy using AWS Certificate Manager Private Certificate Authority and create certificates for various use cases. These use cases include internal applications that terminate TLS, code signing, document signing, IoT device authentication, and email authenticity verification. The workshop covers job functions such as CA administrators, application developers, and security administrators and shows you how these personas can follow the principal of least privilege to perform various functions associated with certificate management. Also learn how to monitor your public key infrastructure using AWS Security Hub.
If any of these sessions look interesting to you, consider joining us in Boston by registering for re:Inforce 2022. We look forward to seeing you there!
Post Syndicated from original https://lwn.net/Articles/897180/
Version 5.1 of the
Tor-oriented Tails distribution has been released. It includes some
improvements to the Tor connection assistant and to handling of
captive-portals, but the most significant change is arguably the delayed fix to a
severe security
vulnerability that had sparked suggestions that some users, at least,
should stop using Tails temporarily.
Post Syndicated from original https://lwn.net/Articles/896918/
In something of a grab-bag session, Josef Bacik led a discussion about
various challenges that Linux kernel maintainers face, some of which lead to
burnout. The session was originally
going to be led by Darrick Wong, but he was unable to come to LSFMM, so
Bacik gathered some of Wong’s concerns and combined them with his own in a
joint storage and filesystem session at the
2022 Linux Storage,
Filesystem, Memory-management and BPF Summit (LSFMM). As part of the
discussion, Bacik presented
his view on what the role of a kernel maintainer should be, which seemed to
resonate with those present.