The PHP project has long shipped under its own license — except for
the parts under the Zend Engine License. The PHP project has now announced
that the PHP license has been retired, and the PHP code has been relicensed
under the three-clause BSD license. See this
blog entry for more details.
Getting here required more than writing an
RFC. The PHP License gives the PHP Group the authority to
change it, which meant tracking down each of the original PHP Group
members and getting their written consent. Each approved the
proposal. Perforce Software, the successor to Zend Technologies,
needed to sign off on the Zend Engine side, as well. They provided
a formal letter confirming their full authority and support for the
change. I hired an attorney to review the proposal and provide
advice on any legal questions that might surface during the
discussion period. Speaking of which, I allowed for a six-month
community discussion period preceding the vote, which passed
unanimously.
DarkSword is a sophisticated piece of malware—probably government designed—that targets iOS.
Google Threat Intelligence Group (GTIG) has identified a new iOS full-chain exploit that leveraged multiple zero-day vulnerabilities to fully compromise devices. Based on toolmarks in recovered payloads, we believe the exploit chain to be called DarkSword. Since at least November 2025, GTIG has observed multiple commercial surveillance vendors and suspected state-sponsored actors utilizing DarkSword in distinct campaigns. These threat actors have deployed the exploit chain against targets in Saudi Arabia, Turkey, Malaysia, and Ukraine.
DarkSword supports iOS versions 18.4 through 18.7 and utilizes six different vulnerabilities to deploy final-stage payloads. GTIG has identified three distinct malware families deployed following a successful DarkSword compromise: GHOSTBLADE, GHOSTKNIFE, and GHOSTSABER. The proliferation of this single exploit chain across disparate threat actors mirrors the previously discovered Coruna iOS exploit kit. Notably, UNC6353, a suspected Russian espionage group previously observed using Coruna, has recently incorporated DarkSword into their watering hole campaigns.
A week after it was identified, a version of it leaked onto the internet, where it is being used more broadly.
This news is a month old. Your devices are safe, assuming you patch regularly.
Фалитът на КТБ се превърна в схема за преразпределение на активи за стотици милиони и дори милиарди. Историята не свърши преди 12 години, когато банката бе закрита, а продължава и…
Looking at the state of the NVIDIA GB10 ecosystem several months down the line, there are a couple of things that have continued to surprise us. The first has been the sheer popularity of the small-form-factor systems, which have seen GB10 boxes from multiple vendors sell almost as fast as they can be produced for […]
This article shows you how to identify and secure open proxies in your AWS environment to prevent abuse, protect your IP address reputation, and control costs.
An open proxy is a server that forwards traffic on behalf of internet users without requiring authentication. While proxies can support legitimate use cases such as load balancing or caching, open proxies allow unrestricted access that threat actors can use to hide harmful activity. In Amazon Web Services (AWS) environments, open proxies often result from misconfigured Amazon Elastic Compute Cloud (Amazon EC2) instances, containers, or compute resources such as AWS Lambda functions. These resources expose proxy functionality without access controls.
Open proxies come in several forms. Common open proxies can include:
HTTP proxies: HTTP proxies forward HTTP requests to web servers, making them useful for web traffic management. These proxies can create potential issues when they’re unsecured.
SOCKS proxies: SOCKS proxies support a wider range of traffic types and provide more flexibility. These proxies create a broader potential for misuse.
Transparent proxies: Transparent proxies intercept traffic without the client’s knowledge and are often used to filter content. These proxies can become security liabilities when misconfigured.
Reverse proxies: Reverse proxies help with internal routing. Unauthorized users can misuse these proxies if they’re exposed.
Knowing these risks can help you better protect your AWS environment.
Security risks
Because of the unrestricted configuration of open proxy servers, threat actors target them to conduct denial of service (DoS) events, intrusion attempts, distribute spam, and other forms of unauthorized activity. These open proxy servers allow threat actors to hide their actual IP address and other forms of identification from the intended targets.
When your AWS infrastructure hosts an open proxy, several risks emerge that can affect both your operations and customers:
Threat actors can misuse your resources, which can result in your IP address being added to security service and reputation system block lists. This can affect your legitimate business operations and customer access. When external parties use your infrastructure for harmful activities, the reputation damage extends beyond immediate technical concerns to affect your ability to reach customers and partners.
Unexpected costs from resource consumption occur when threat actors use your bandwidth and compute capacity. The traffic patterns that proxy abuse generate can also alert AWS security monitoring systems and create additional operational overhead as you investigate and respond to these alerts.
Service disruptions might affect your legitimate workloads because unauthorized traffic competes for resources with your business-critical applications. This competition for resources can potentially degrade performance or cause availability issues for your customers.
Implementing security measures
To prevent the risks associated with open proxies, it’s essential to implement proper security controls for proxy services in AWS environments. The following guidance is a comprehensive approach that you can follow to secure your proxy infrastructure.
Access control implementation
An important security step is to use passwords and authentication mechanisms to restrict access to proxy services. Configure your proxies to accept connections only from known, trusted IP address ranges. For Elastic Load Balancing (ELB), limit access based on source IP addresses and add authentication to proxies behind the load balancers. When you create new instances in Amazon Elastic Kubernetes Service (Amazon EKS), limit access to your balancer in each instance. If instances don’t have public IP addresses, then you can limit access to the balancer instead. If instances have public IP addresses, then you must limit access to those IP addresses.
When possible, use AWS PrivateLink virtual private cloud (VPC) endpoints to provide private connectivity to AWS services without exposing them to the internet. Deploy proxy services in private subnets with controlled outbound access through NAT gateways or other controlled channels. For Amazon EC2 and Amazon Lightsail resources, update the attached security group to prevent public internet access. To secure the proxy, you must either limit access to specific IP addresses or implement authentication on the endpoint.
Authentication and authorization
Turn on authentication for the proxy software and use strong credentials, certificates, or integration with AWS Identity and Access Management (IAM) and AWS Directory Service. Apply IAM policies with the principle of least privilege to limit access to only what users need to perform their tasks. This approach reduces the potential effects of credential compromise and helps maintain clear accountability for resource access.
Monitoring and detection
To detect unusual proxy activity, configure Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, AWS CloudTrail, and Amazon GuardDuty. Use Amazon CloudWatch alarms to notify you of abnormal traffic patterns that might indicate unauthorized use of your proxy services. These monitoring capabilities provide visibility into your network traffic patterns and help you identify both legitimate usage and potential security concerns.
Deployment best practices
Use HTTPS for ELB traffic to protect data in transit, and restrict security groups to necessary ports to minimize the surface area for potential misuse. Integrate AWS WAF with balancers to filter web traffic based on rules that you define. You can also use AWS Network Firewall for advanced traffic filtering capabilities. For APIs, deploy Amazon API Gateway with authentication and authorization controls to manage access to your backend services. This layered approach to security helps protect your infrastructure at multiple points in the traffic flow.
Regular security assessments
Run Amazon Inspector to scan for misconfigurations in your infrastructure, and use AWS Security Hub to centralize security findings across your AWS environment. Conduct penetration tests in accordance with AWS policy to identify potential security issues before they can result in unintended access.
Incident response planning
Automate remediation with AWS Config rules and Automation, a capability of AWS Systems Manager, to respond rapidly to security events. Maintain incident response runbooks that outline clear steps for addressing proxy-related security incidents, and decommission unused resources that could become security liabilities.
Documented procedures and automated responses reduce the time between detection and remediation and minimizes the potential effects of security incidents on your operations.
Benefits of proper proxy security
When you implement these security measures, you gain the following advantages for your AWS environment:
Protection of your IP address reputation helps maintain customer trust and prevents security services from blocking your legitimate traffic. When your infrastructure maintains a positive reputation, your business communications reach their intended recipients without interference.
Cost control prevents unauthorized users from consuming your AWS resources and generating unexpected charges on your account. When you restrict access to legitimate users and use cases, you maintain predictable costs that align with your business needs.
Operational stability reduces the risk of service disruptions that abuse of your proxy infrastructure can cause. When you dedicate your resources to serving your customers rather than supporting unauthorized activity, you can deliver consistent performance and availability.
Enhanced visibility into your network traffic patterns helps you identify both legitimate usage and potential security concerns. This awareness allows you to make informed decisions about capacity planning, security improvements, and operational optimizations.
Conclusion
Open proxies present a serious risk in AWS environments, but you can effectively secure proxies with the right measures. By implementing strict access controls and additional security practices such as authentication, monitoring, and regular assessments, you can prevent misuse, protect your infrastructure, and maintain your IP address reputation.
Taking proactive steps strengthens your own environment and supports the broader security of the internet ecosystem. Under the AWS shared responsibility model, you’re responsible for the configuration and maintenance of these security controls, while AWS provides the underlying secure infrastructure. By following the guidance in this article, you can build a robust security posture that protects your proxy infrastructure while supporting your legitimate business needs.
If you have feedback about this post, submit comments in the Comments section below.
Last week, I took some time off in York, England, often described as the most haunted city in the country. I wandered through the ruins of abbeys that have stood for nearly a thousand years, walked along medieval walls, and spent an evening on a ghost tour hearing stories passed down through centuries. There’s something grounding about standing in a place that has witnessed so much history. Now I’m back at my desk, and the contrast is hard to miss: those abbey stones have stood for a thousand years largely unchanged, while in the span of a single week away, the pace of technological change has moved forward yet again.
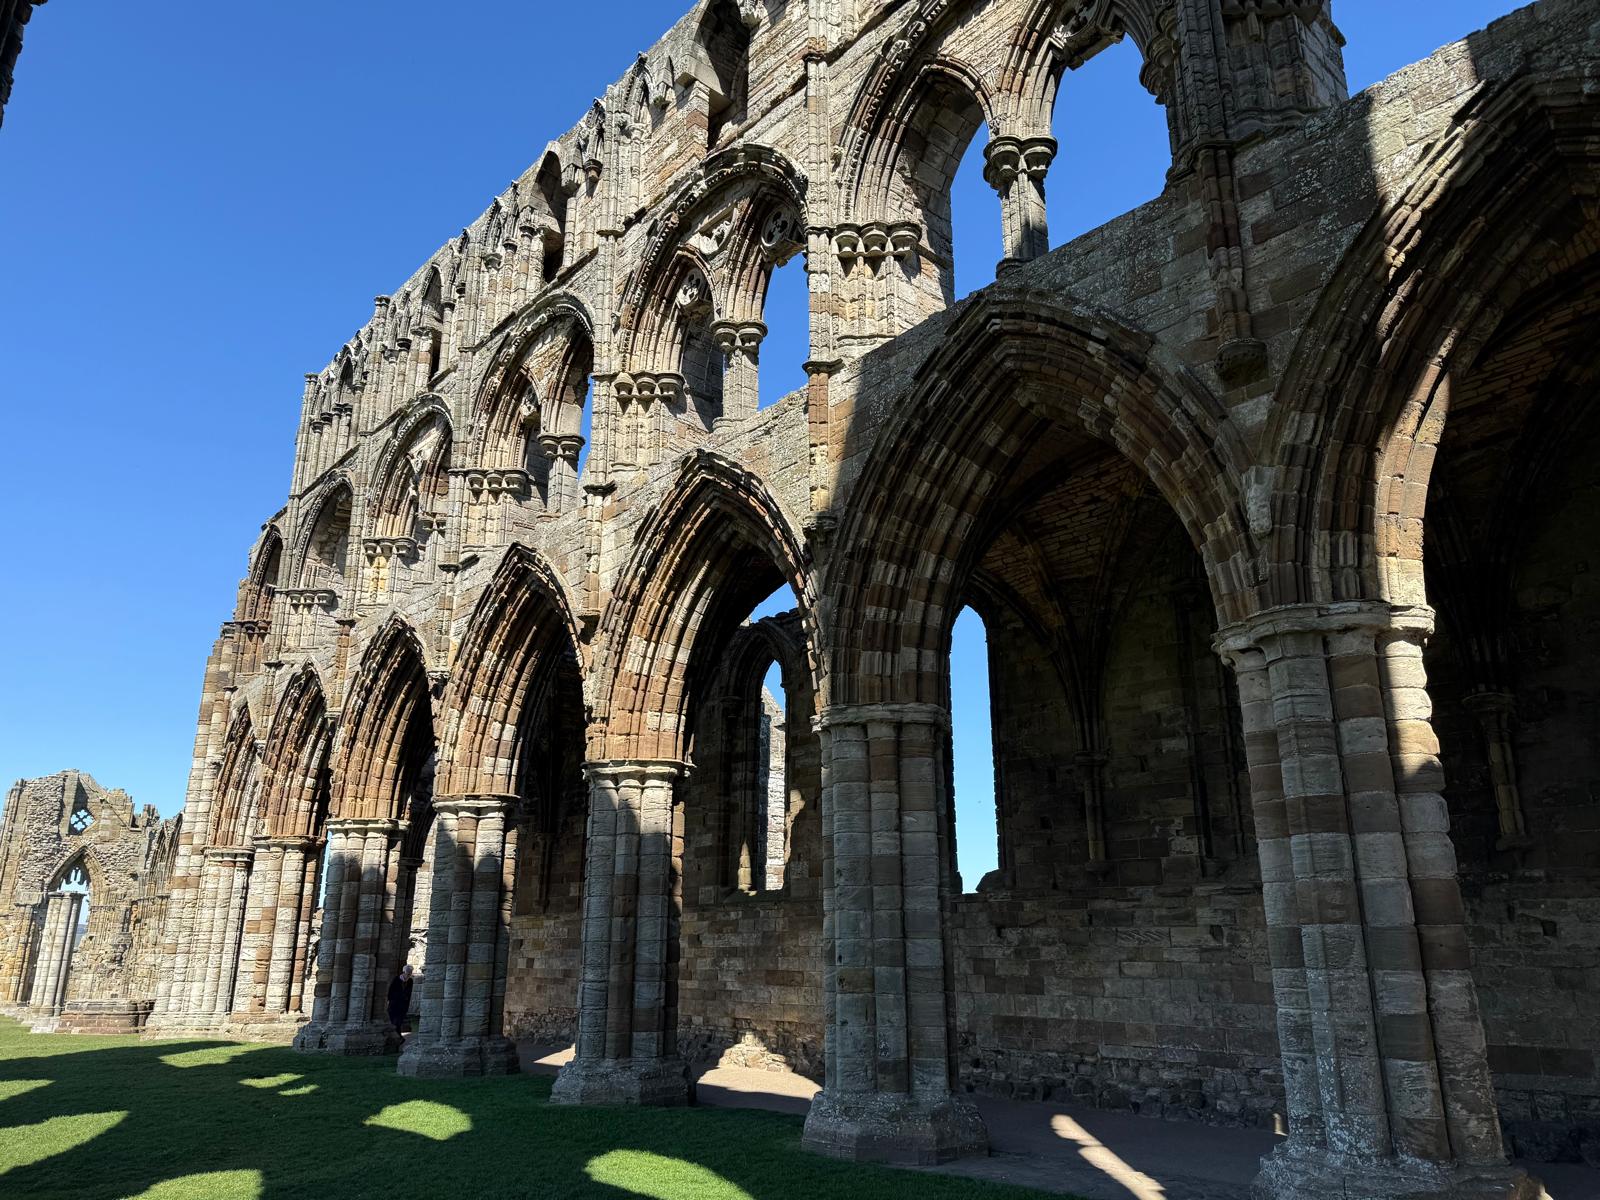
The ruins of Whitby Abbey in North Yorkshire. Stones that have seen a thousand years, while this week alone brought another wave of change.
Now, let’s get into this week’s AWS news.
Headlines On April 28, Matt Garman, CEO of AWS, Colleen Aubrey, SVP Amazon Applied AI Solutions, Julia White, CMO of AWS, and OpenAI leaders took the stage to share how customers are changing the way businesses operate with agents. The event brought a packed slate of announcements across Amazon Quick, Amazon Connect, and a deeper partnership with OpenAI. Here’s a roundup of the biggest announcements from the event.
Amazon Quick expands with a desktop app, new pricing plans, and visual asset generation – Amazon Quick is an AI assistant for work that connects to your apps, learns what matters to you, and takes action on your behalf. This week, Quick introduced a new desktop app (Preview) that keeps you connected to your local files, calendar, and communications without opening a browser. You can sign up within minutes using your personal email address or existing Google, Apple, Github, or Amazon credentials—no AWS account required. Quick can now generate polished documents, presentations, infographics, and images directly from the chat interface, and native integrations expand to include Google Workspace, Zoom, Airtable, Dropbox, and Microsoft Teams. A new Build custom apps with Quick capability (Preview) lets you create intelligent apps, dashboards, and web pages connected to the rest of your business using natural language.
Amazon Connect expands into four agentic AI solutions – Amazon Connect is expanding from a single product into a set of four agentic AI solutions designed to work within your existing workflows. Amazon Connect Decisions is a supply chain planning and intelligence solution that shifts teams from crisis management to proactive planning, combining 30 years of Amazon operational science with more than 25 specialized supply chain tools. Amazon Connect Talent (Preview) is an agentic AI hiring solution that delivers AI-led interviews, science-backed assessments, and consistent evaluation for talent acquisition leaders managing scaled hiring. Amazon Connect Customer, previously known as Amazon Connect, delivers personalized customer experiences across voice, chat, and digital channels, with new configuration capabilities that enable organizations to set up conversational AI in weeks rather than months. Amazon Connect Health delivers agentic patient verification, appointment management, patient insights, ambient documentation, and medical coding, giving patients faster access to care and clinicians more time to deliver it.
AWS and OpenAI expand their partnership across Amazon Bedrock – AWS and OpenAI are bringing the latest OpenAI models to Amazon Bedrock, launching Codex on Amazon Bedrock, and introducing Amazon Bedrock Managed Agents powered by OpenAI — all in limited preview. OpenAI models on Amazon Bedrock (Limited preview) brings the latest OpenAI models, including GPT-5.5 and GPT-5.4, to the Bedrock APIs you already use, with unified security, governance, and cost controls. No additional infrastructure to configure, no new security model to learn. Codex on Amazon Bedrock (Limited preview) lets you access the OpenAI coding agent within your existing AWS environments, authenticating with your AWS credentials, processing inference through Bedrock, and applying Codex usage toward your AWS cloud commitments. Codex on Bedrock is available through the Bedrock API, starting with the Codex CLI, the Codex desktop app, and a Visual Studio Code extension. Amazon Bedrock Managed Agents, powered by OpenAI (Limited preview) combines OpenAI frontier models with AWS infrastructure to build production-ready OpenAI-powered agents in the cloud, built with the OpenAI harness for faster execution, sharper reasoning, and reliable steering of long-running tasks.
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Amazon EC2 M8in and M8ib instances are now generally available – Powered by custom 6th-gen Intel Xeon Scalable processors and 6th-gen AWS Nitro cards, these instances deliver up to 43% higher performance over M6in and M6ib. M8in offers 600 Gbps network bandwidth, while M8ib delivers up to 300 Gbps EBS bandwidth. Available in US East (N. Virginia), US West (Oregon), Asia Pacific (Tokyo), and Europe (Spain).
Amazon EC2 R8in and R8ib instances are now generally available – Memory-optimized instances built on the same 6th-gen Intel Xeon Scalable processors and Nitro cards, with the same 600 Gbps network and 300 Gbps EBS bandwidth profiles. Well-suited for large commercial databases, data lakes, and in-memory databases such as SAP HANA. Available in US East (N. Virginia, Ohio), US West (Oregon), and Europe (Spain).
Amazon EC2 C8ine and M8ine instances are now generally available – Network-optimized instances offering up to 2.5x higher packet performance per vCPU and up to 2x higher network throughput for traffic through internet gateways compared to C6in and M6in. Designed for security and network virtual appliances including virtual firewalls, load balancers, and 5G UPF workloads. Available in US East (N. Virginia), US West (Oregon), and Asia Pacific (Tokyo) for C8ine; US East (N. Virginia) and US West (Oregon) for M8ine.
Amazon Bedrock AgentCore adds optimization capabilities (Preview) – AgentCore now offers recommendations, batch evaluations, and A/B tests to complete the observe-evaluate-improve loop for agents in production. Recommendations analyze production traces and evaluation outputs to propose optimized system prompts and tool descriptions, which you can validate with batch evaluations against pre-defined test cases or A/B tests against live traffic. Every recommendation requires your approval before it ships.
AWS Lambda adds support for Ruby 4.0 – Ruby 4.0, the latest LTS release, is available as a Lambda managed runtime and container base image. It includes support for Lambda advanced logging controls, including JSON structured logs, configurable logging levels, and target CloudWatch log group configuration. Available in all AWS Regions, including China Regions and AWS GovCloud (US).
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news Here are some additional posts and resources that you might find interesting:
Amazon Q Developer end-of-support announcement – Amazon Q Developer IDE plugins and paid subscriptions will reach end of support on April 30, 2027, giving customers 12 months to transition to Kiro. New signups will be blocked starting May 15, 2026, although existing subscriptions can continue to add users. Starting May 29, 2026, Opus 4.6 will no longer be available on Q Developer Pro; Opus 4.5 and other existing models remain available, and the latest coding models including Opus 4.7 are available exclusively on Kiro. Amazon Q Developer in the AWS Management Console and first-party AWS experiences (documentation, mobile app, Slack, and Microsoft Teams) are not affected.
AWS 10,000 AIdeas Competition: Meet the Winners – AWS announced the 20 winners of the 10,000 AIdeas Competition, a global challenge where builders submitted AI applications built entirely with Kiro and the AWS Free Tier, with submissions from 115 countries narrowed down through four rounds of evaluation and two rounds of community voting. Winners span Global Champions, Regional Champions, Innovation Awards, and Creative Track categories, with cash prizes and AWS credits awarded across each tier.
AWS Student Builder Groups – AWS Cloud Clubs is evolving to AWS Student Builder Groups. The community now spans 600+ colleges and universities across 63 countries. Existing Cloud Club memberships, badges, and progress carry forward, and Cloud Club Captains become Group Leaders. Membership is open to any learner 18 or older. You can find a group near you on AWS Builder Center or apply to launch a new group on your campus.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
As Netflix has grown, machine learning continues to support our ability to deliver value to members and drive excellence across multiple areas of our business. When Netflix began investing in machine learning over a decade ago, it was primarily focused on a single domain: personalization. Scala was the industry standard, our ML teams were relatively small, and optimizing member engagement was our primary use case. Fast forward to today, and machine learning has become the backbone of Netflix’s business transformation. We now apply ML across various business domains, including:
Personalization: Optimizing engagement and helping members discover content they’ll love
Studio: Pre and post-production workflows
Payments: Fraud detection, payment routing, and recurring billing optimization
Ads: Our newest domain, requiring real-time decisioning and targeting
… and a growing number of additional use cases across the company
Each domain operates with a different tech stack, different business metrics, and a distinct organizational structure. While this diversity is a testament to how machine learning has evolved to drive value across many verticals at Netflix, this growth introduces a new challenge: enabling cross-pollination of models and data across domains.
The Challenge: A Fragmented ML Landscape
As our ML investments scaled across these domains, a critical problem emerged: the models produced largely became black boxes. Without any discovery infrastructure, ML practitioners couldn’t easily collaborate or share work across business verticals.
Consider a concrete example: content embeddings. Our Studio teams create sophisticated embeddings that identify scene boundaries, detect visual transitions, and understand content structure. These embeddings were originally built for production workflows.
But those same embeddings could be incredibly valuable elsewhere. Ads could hypothetically use content embeddings for context matching (ensuring advertisements align with the tone and content of what’s currently playing). Personalization could leverage them for episodic merchandising and recommendations (matching the topic or mood of an episode with a user’s preferred viewing preferences). Yet making this cross-pollination happen is extraordinarily difficult.
Why? Our ML tools exist in silos, each with its own backend services and user interface. The model registry is unaware of which A/B tests were using its models, and the pipeline orchestrator is unaware of downstream model dependencies. ML practitioners have to traverse multiple systems to answer basic questions about their work. Finding a model requires opening the model registry, understanding its lineage means switching to the pipeline orchestrator, and tracking which A/B tests use that model requires navigating to the experimentation platform. This fragmentation prevents practitioners from answering critical questions:
Discovery: What features exist? What data sources are available for generating features for a model?
Lineage: Which pipeline is generating data for a specific model? What data sources feed those features?
Impact: Which A/B tests are running this model? Which models will break if I change this feature? Who owns each piece of this chain?
The Hard Problem: Connecting everything
The real challenge wasn’t just building a consolidated UI. We needed to connect the different pieces of infrastructure our ML practitioners were using to perform different parts of the ML lifecycle.
Our ML ecosystem generates metadata from dozens of sources:
Pipeline orchestration systems emit execution details, stage dependencies, and data transformations
Deployed model registry tracks model versions, artifacts, staleness, and deployment history
Experimentation platform manages A/B tests and their configurations
Feature store catalog feature definitions and usage
AI Dataset platform tracks the creation, management, discovery, and loading of datasets.
Identity platform maintains user, team, and organization metadata
Each system employs different formats, identifiers, and mental models. The hard technical problem we had to solve was: How do we collect this heterogeneous metadata, transform it into a unified entity model, and build a connected graph that enables true exploration and collaboration across business domains?
The Solution: Metadata Service and the Model Lifecycle Graph
Our answer was the Metadata Service (MDS), which builds a Model Lifecycle Graph that indexes and connects ML-related entities across Netflix. MDS is optimized for real-time ingestion of ML metadata (e.g., models, features, pipelines, experiments, datasets) and to answer cross-domain questions such as “Which experiments are running this model?” or “Which models share these features?” It is the foundation that enables discovery, ingesting events from diverse sources, enriching them with context, and materializing relationships across entities.
Our vision: to make every ML asset at Netflix discoverable, understandable, and reusable by every ML practitioner, regardless of their team or domain.
Core Abstractions: The Vocabulary of the System
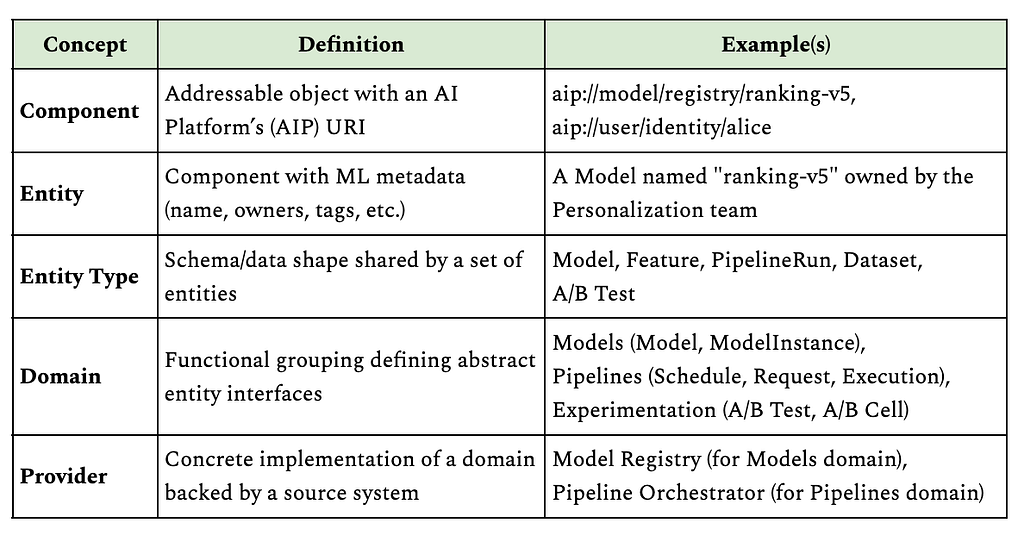
Before diving into the technical implementation, it’s helpful to understand the conceptual model that underpins MDS. This vocabulary enables consistent communication across teams and systems:
Component: Any object that is uniquely addressable using an AI Platform’s (AIP) Uniform Resource Identifier (URI). An AIP URI follows the formataip://<componentType>/<platformId>/<resourceId>, ensuring global uniqueness. For example:
Entity: A component within the ML ecosystem, characterized by additional properties such as name, description, creation date, and owners. Entities represent ML-specific assets, such as models, features, and pipelines.
Entity Type: A group of entities that share the same data shape. A data shape is a set of property constraints that specify the attributes and relationships an entity must have.
Domain: A functional grouping of related entity types that defines the abstract interface for a category of ML assets. For example, the Models domain defines what a Model and Model Instance look like, while the Pipelines domain defines Schedules, Requests, and Executions.
Provider: A concrete implementation of a domain, backed by a specific source system. For example, the Models domain is currently backed by our internal model registry. This separation allows MDS to support multiple providers for the same domain. If a new model registry were introduced, it could be added as an additional provider without changing the domain interface.
We can summarize these concepts with a concrete example:
This URI-based addressing scheme is crucial as it allows any service to reference any ML asset with a single string, and MDS can resolve that reference back to rich, connected metadata.
From Events to Entities to Graph
The journey from raw system events to a queryable graph happens in stages. Let’s walk through each with a concrete example: connecting a model to its A/B tests through relationship inference.
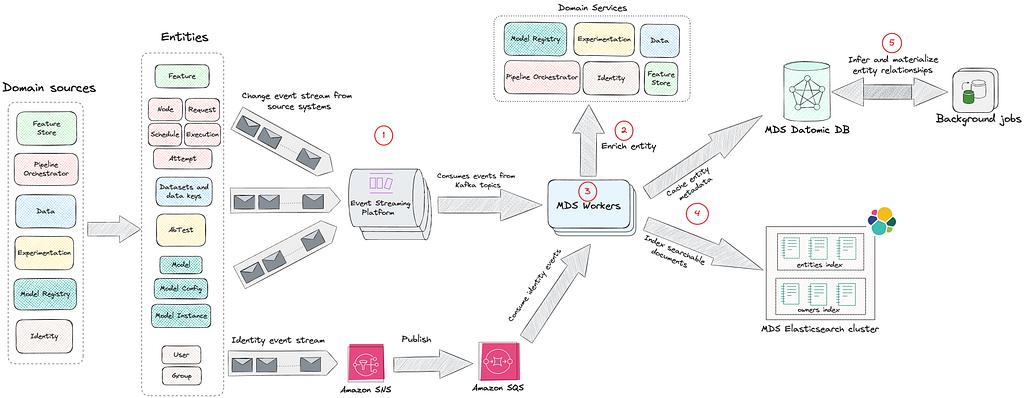
1 Event Ingestion
MDS integrates with various source systems via Kafka and AWS SNS/SQS, consuming events in real-time. Source systems emit thin events that include an identifier and an event type.
This design keeps producers simple. Source systems only need to announce that a change occurred, without building complete payloads or understanding downstream requirements.
Each source system has dedicated event handlers in MDS:
Pipeline Orchestration: Ingests pipeline execution events, including node definitions, schedules, requests, and job attempts
Model Registry: Captures model deployments, configurations, and version updates
Feature Store: Tracks feature definitions and their versions
Experimentation Platform: Monitors A/B test configurations and allocations
Datasets: Tracks ML datasets and their versions
Identity Platform: Maintains ownership and team membership information
2 Entity Enrichment
MDS implements a hydration contract for each event type. When an event arrives, MDS:
Validates the event schema
Calls the source system’s API to fetch the complete, current state
Transforms the response into a normalized entity
This design has a crucial property: the order of events doesn’t matter. MDS always fetches the latest facts from the source of truth. This pattern decouples the event stream from state consistency. If the event bus drops a message or delivers it out of order, the next event corrects the state. The event stream becomes a notification of change rather than a log of changes.
This notification of change pattern has a few important tradeoffs. On the plus side, it keeps producers simple, makes us robust to out-of-order or dropped events, and ensures that MDS can always reconcile to the latest state by reading from the source of truth. The tradeoff is that we place additional read load on source systems during hydration and need to be deliberate about rate limiting, caching, and backoff in our enrichment workers so that we don’t overload them.
For our ranking model example, when the model_instance_created event arrives, MDS calls the Model Registry API: GET /api/v1/instances/ranking-model-v5-20XX0101
The registry responds with a full descriptor. Example response (key fields only):
Raw events are heterogeneous and each source system has its own schema and semantics. MDS workers transform these events into a unified entity model with standardized fields.
Without normalization, downstream consumers would need to understand every source system’s schema. Normalization creates a consistent interface, allowing queries and relationships to work across all entity types. Here is an example.
The normalization process standardizes field names and formats. For example, platform-specific IDs become global AIP URIs, owner_emails becomes owners with resolved user URIs, and labels become tags. Foreign keys like pipeline_run_id are transformed into entity references. However, there’s still no reference to which A/B tests are using this model. The Model Registry doesn’t track experiments, and the Experimentation Platform doesn’t track which pipeline produced a given model. This is where knowledge enrichment becomes critical.
4 Storage and Indexing
Once normalized, entities are persisted to Datomic and immediately indexed in Elasticsearch. This happens synchronously within the event processing flow.
Datomic for Caching and Relationships Normalized entities are first written to Datomic, which serves as both a local cache and a graph database.
Why Datomic? Datomic serves as both the system of record for MDS and the working dataset for enrichment processes. Its immutable fact model means we can continuously add relationships without losing the original entity state.
What we store:
All entity attributes as facts
Entity references (foreign keys that may point to entities not yet fully resolved)
All relationships as reified edges (added by enrichment processes)
Entity lifecycle state (tracking which entities are fully enriched vs awaiting hydration)
This enables:
Complex graph traversals: Navigate from a model to its features to their data sources in a single query
Entity relationships: Join across multiple domains without N+1 query problems
Flexible schema evolution: Easy to add new entity types and attributes as the catalog grows
Progressive enrichment: Background jobs efficiently identify and process entities requiring additional hydration, enabling gradual graph completion without reprocessing fully enriched entities
In practice, we use Datomic for relationship-heavy, navigational queries such as:
Starting from this model instance, show me all upstream datasets and downstream experiments.
Given this feature, list all consuming models and their owning teams.
These queries often span multiple hops in the graph and benefit from Datomic’s immutable fact model and efficient joins across entity relationships.
Elasticsearch for Discovery Immediately after writing to Datomic, entities are indexed in Elasticsearch to power fast, full-text search across the catalog.
Single entities index: All entity types (models, features, pipelines, etc.) are indexed in one unified index, differentiated by the entityType field
Separate owners index: Dedicated index for users and groups to enable cross-entity owner searches
Relevance boosting: Exact name matches score higher than other relevant matches
This enables:
Multi-field text search across entity names, descriptions, tags, and related metadata
Relevance ranking with boosting (exact name matches score significantly higher)
Complex filtering by entity type, ownership, tags, and domain-specific attributes (stored as tags)
Fuzzy matching to handle typos and partial queries
Elasticsearch powers the entry point into the system: users typically start with a free-text search in the AIP Portal (for a model name, a team, or a domain term), and then switch to graph navigation once they land on an entity page. Indexing happens in near real-time as part of the ingestion and enrichment workflows, so changes are usually visible in the Portal with a short delay that is acceptable for interactive use.
5 Knowledge Enrichment and Graph Formation
Once entity metadata is persisted in Datomic, scheduled background processes take over to discover and materialize relationships. These enrichment jobs run periodically, scanning for uncached or partially resolved entities (entities that exist only as references without full metadata).
The enrichment workflow:
Identify candidates: Find entities marked as uncached or with unresolved references
Hydrate relationships: Query source-of-truth systems to fetch related entity details
Materialize edges: Write discovered relationships back to Datomic
Re-index: Trigger Elasticsearch indexing for updated entities
Mark as enriched: Update entity status to prevent redundant processing
This asynchronous approach allows MDS to handle the computational cost of graph formation without blocking real-time event ingestion. It also enables retry logic and gradual enrichment as new entities become available.
Because enrichment is asynchronous, newly discovered relationships may appear with a short delay after the underlying entities are created (typically minutes rather than seconds). We track when each entity was last enriched and surface this timestamp in the AIP Portal, so practitioners can reason about staleness and know when it’s safe to rely on a particular relationship for debugging or impact analysis.
Why enrich? Source systems are purpose-built and don’t know about entities in other domains. Enrichment discovers and materializes cross-system relationships that enable powerful lineage and impact queries.
Example: Connecting Models to A/B Tests
When MDS processes a new model instance, background enrichment jobs discover relationships through multi-hop inference:
Step 1: Direct link to pipeline
The model references a pipeline_run_id. An enrichment job hydrates the pipeline and discovers its A/B test associations: GET /api/v1/pipeline-runs/train-weekly-ranking-20XX0101
Step 2: Discover A/B test context The enrichment job discovers the pipeline ran for A/B test cell #2 and queries the Experimentation Platform for test details: GET /api/v1/tests/12345
{
 "test_id": "12345",
 "name": "Ranking Model v5 vs v4",
 "status": "ACTIVE",
 "cells": [{"cell_number": 1, "name": "control_ranking_v4"}],
 ...
}
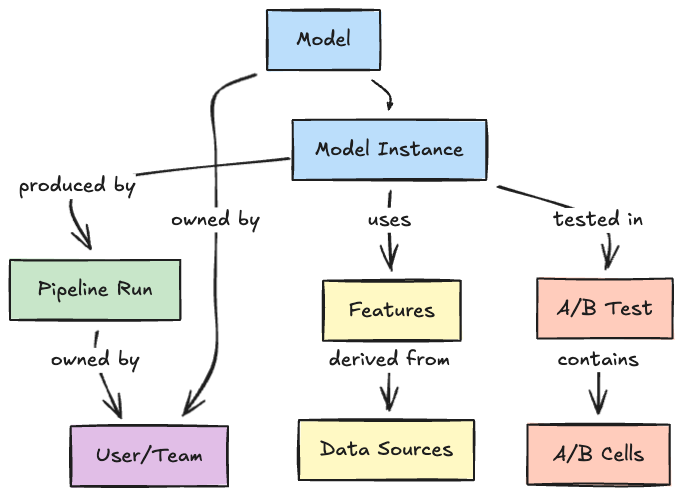
Step 3: Infer transitive relationships The enrichment job now has the complete chain:
Model Instance was produced by Pipeline Run
Pipeline Run was executed for A/B Test Cell #2
The A/B Test Cell #2 belongs to A/B Test “Ranking Model v5 vs v4”
Model Instance now gets associated with this A/B Test
The job writes the inferred relationship back to Datomic and triggers re-indexing, and materializes these edges in the graph. MDS doesn’t just store what it’s told; it derives new knowledge by walking the graph in the background.
Why this matters: Without MDS, answering “Which A/B tests are using this model?” requires:
Looking up the model in the Model Registry
Finding which pipeline produced it
Checking the Pipeline Orchestrator for A/B test tags
Querying the Experimentation Platform for test details
With the model lifecycle graph, it’s a single query:
query {
  model(id: "aip://model/registry/ranking-model-v5-20XX0101") {
    name
    owners { name }
    currentInstance {
      version
      pipeline {
        name
        owners { name }
      }
      features {
        edges {
          node {
            name
            data { edges { node { name } } }
          }
        }
      }
      associatedAbTests {
        name
        cells { number name }
      }
    }
  }
}
The reverse query also works: “What models are being tested in experiment 12345?”
Enabling Exploration, Not Just Search
With the Model Lifecycle Graph in place, we shift from entity search to entity exploration. Discovery isn’t just about finding a model; It’s about traversing relationships:
Start with a model, explore its features
From features, navigate to the core data driving them
From the data, trace back to the pipelines generating it
From pipelines, see which teams own and depend on them
From experiments, understand which models are being tested
For example, imagine an engineer investigating a degraded engagement metric for a personalization model. They might:
Start with the model instance powering the affected recommendations in the AIP Portal.
Inspect the model’s features and follow a suspicious feature to its upstream dataset.
From the dataset page, see that its pipeline recently had failed runs and identify the owning team.
Confirm which A/B tests are currently running this model instance to understand which members and surfaces are impacted.
Before MDS and the Model Lifecycle Graph, this required manual checks across multiple tools (model registry, pipeline orchestrator, experiment platform). Now it’s a contiguous journey in a single interface.
This graph-based exploration answers questions that were previously impossible:
Lineage queries: What is the complete lineage of this model, from training data to production experiments?
Impact analysis: Which models will be affected if I change this feature?
Usage discovery: Which A/B tests are using this model?
Dependency mapping: What data sources does my pipeline transitively depend on?
Deprecation planning: Which entities are no longer being used and can be retired?
Every entity has deep context: its creation time, ownership, update history, and most importantly, its relationships to other entities.
The Model Lifecycle Graph is surfaced to practitioners through the AIP Portal, a unified interface that provides full-text search across all entity types, detailed entity pages with navigable relationships, and personalized views for teams and individuals.
A typical interaction in the AIP Portal looks like:
Search: Type a model, feature, dataset, or team name into the single search box backed by Elasticsearch.
Inspect: Land on an entity page that shows key metadata (description, owners, domains, tags) alongside a relationships panel.
Explore: Click through to related entities (upstream datasets, downstream experiments, and sibling model versions) to navigate the Model Lifecycle Graph without leaving the portal.
When new entity types are introduced into MDS, the portal automatically provides baseline search, entity pages, and relationship navigation, and we can then layer on domain-specific visualizations (such as model deployment history or dataset version timelines) over time.
The Road Ahead: Open Challenges
Building the ML lifecycle graph is an ongoing journey. Significant challenges remain, and these represent the future opportunities for us:
Tool Proliferation: As new ML tools emerge, we need robust integration patterns that scale. How do we design plugin architectures that make adding new sources seamless? If we don’t keep up with new tools, practitioners will be forced back into fragmented views, and the Model Lifecycle Graph will lose coverage and trust.
Domain-Specific Visualizations: Different entity types require distinct visualization experiences. Model pages should display deployment history, A/B test associations, and performance metrics. Feature pages should highlight data lineage and consuming models. Pipeline pages must show execution history, dependencies, and schedules. Dataset pages require versioning timelines and downstream consumers. How do we design a flexible UI framework that allows each entity type to have its own tailored experience while maintaining consistent navigation and interaction patterns across the portal? Without rich, domain-specific experiences, the portal risks becoming a generic catalog rather than a tool that ML practitioners rely on in their daily workflows.
Metadata Quality: Today, MDS ensures data consistency through source-of-truth hydration and schema validation at ingestion. Background enrichment jobs continuously infer relationships and materialize entities from source systems. However, challenges remain in ensuring completeness and timeliness at scale. When source systems fail to emit events, when ownership information becomes stale, or when entities lack descriptions and contextual metadata, the graph’s utility degrades. How do we build automated validation and enrichment systems to detect metadata anomalies, suggest missing relationships, and maintain quality benchmarks across millions of entities? Poor or stale metadata erodes practitioner trust: if the graph is incomplete or incorrect, teams will revert to ad hoc knowledge and one-off integrations rather than using MDS as their source of truth.
Advanced Relationship Inference: Beyond explicit relationships declared in source systems, how do we infer implicit connections? Can we detect that two models serve similar purposes based on shared features? Can we recommend features based on usage patterns from similar pipelines? We are in the early stages of exploring these ideas. Done well, they would turn MDS from a passive catalog into an active recommendation engine for ML assets, accelerating reuse and reducing duplicate work across domains.
The Alpine Linux account on fosstodon.org reports
that all systems hosted at Linode, including its GitLab instance,
“are suspended at the moment due to some billing issue“. They
are working to get it resolved, but in the meantime all of their
services appear to be down.
For a number of years, users submitting bugs reports against GNOME packages in Fedora have
received an auto-reply saying that the reports were not actively
monitored; users were encouraged to file bugs with GNOME upstream instead. However,
that practice seems to be in conflict with the Fedora Engineering Steering
Committee (FESCo) policy
that package maintainers “deal with reported bugs in a timely manner“. On
April 28, FESCo discussed the disconnect between practice and policy; so far,
it has only opted to tweak the wording of the automatic response.
Version 5.0.0
of the NetHack
dungeon-exploration game, a distant relative of Rogue and Hack, has been released. NetHack’s code is now compliant with the
C99 standard, and the release includes more than 3,100
bug fixes and changes, detailed in doc/fixes5-0-0.txt
(may contain game spoilers). Saved games from previous versions will
not work with NetHack 5.0.0.
Polymarket is a platform where people can bet on real-world events, political and otherwise. Leaving the ethical considerations of this aside (for one, it facilitates assassination), one of the issues with making this work is the verification of these real-world events. Polymarket gamblers have threatened a journalist because his story was being used to verify an event. And now, gamblers are taking hair dryers to weather sensors to rig weather bets.
The second 7.1 kernel prepatch is out for
testing. “It’s not small, and while it’s a bit early to say for sure, I
do suspect we’re seeing the same continued pattern of more patches than
usual – probably due to AI tooling – that we saw in 7.0.“
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.