Tag Archives: Amazon SNS

Accelerating AWS Network Firewall troubleshooting with AWS DevOps Agent

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/security/accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent/

When an administrator introduces a rule change in AWS Network Firewall and network connectivity is disrupted, pinpointing the cause requires inspecting multiple points in the traffic path. The firewall gives you stateless and stateful rule engines, domain rules, and routing to the firewall endpoint inside your Amazon Virtual Private Cloud (Amazon VPC). A network drop looks the same from the workload no matter where it started. Isolating the cause means correlating the alert and flow logs with the firewall configuration, route tables, and recent API calls in AWS CloudTrail that might have changed them. That manual correlation is exactly where AWS DevOps Agent helps, accelerating root cause analysis so you can restore connectivity in minutes instead of hours.

AWS DevOps Agent does that correlation for you. As your always-available operations teammate, it resolves and proactively prevents operational issues across AWS, multicloud, and on-premises environments. When an Amazon CloudWatch alarm triggers, it reaches the agent through a webhook. The agent then reads the firewall configuration and logs through AWS APIs, ties the drop to recent API activity, and returns a root cause with a mitigation plan you review before you apply it.

This post connects CloudWatch monitoring to DevOps Agent. It walks through three Network Firewall failures from end to end. The first is a domain deny list blocking a legitimate endpoint. The second is a stateless rule priority misconfiguration. The third is an asymmetric cross Availability Zone (AZ) routing drop. Each maps to a different layer, so each leads down a different investigation path. An AWS Cloud Development Kit (AWS CDK) app deploys the whole environment in your own account so you can reproduce each failure and follow along.

The sample workload

As part of this blog post, we provide a CDK stack that deploys both the AWS DevOps Agent Space and a sample workload used to walk through three separate troubleshooting scenarios. A single t3.micro instance in a protected subnet checks its connectivity to a test endpoint on a continuous loop and publishes results to CloudWatch. Traffic takes the internet egress path through Network Firewall, the NAT gateway, and the internet gateway, so the firewall can intercept or drop it. After completing the walkthrough, you can apply the same troubleshooting techniques with DevOps Agent against your own Network Firewall deployments.

The test endpoint runs in a separate VPC deployed by the same CDK app. It serves HTTPS on port 443 and TCP on port 9142, giving each scenario a different protocol layer to exercise: Scenario 1 targets a TLS connection on 443 (matched by Server Name Indication), Scenario 2 targets a TCP connection on 9142, and Scenario 3 exercises the whole egress path.

A live status page shows one card per scenario plus the network topology. The whole stack deploys from a single CDK app across two Availability Zones, each with a firewall endpoint and NAT gateway, which is what makes Scenario 3 possible.

As shown in the following figure, the egress data path runs from the workload through Network Firewall and the NAT and internet gateways to the test endpoint. The alarm pipeline runs from CloudWatch through Amazon Simple Notification Service (Amazon SNS) and the webhook AWS Lambda function to DevOps Agent.
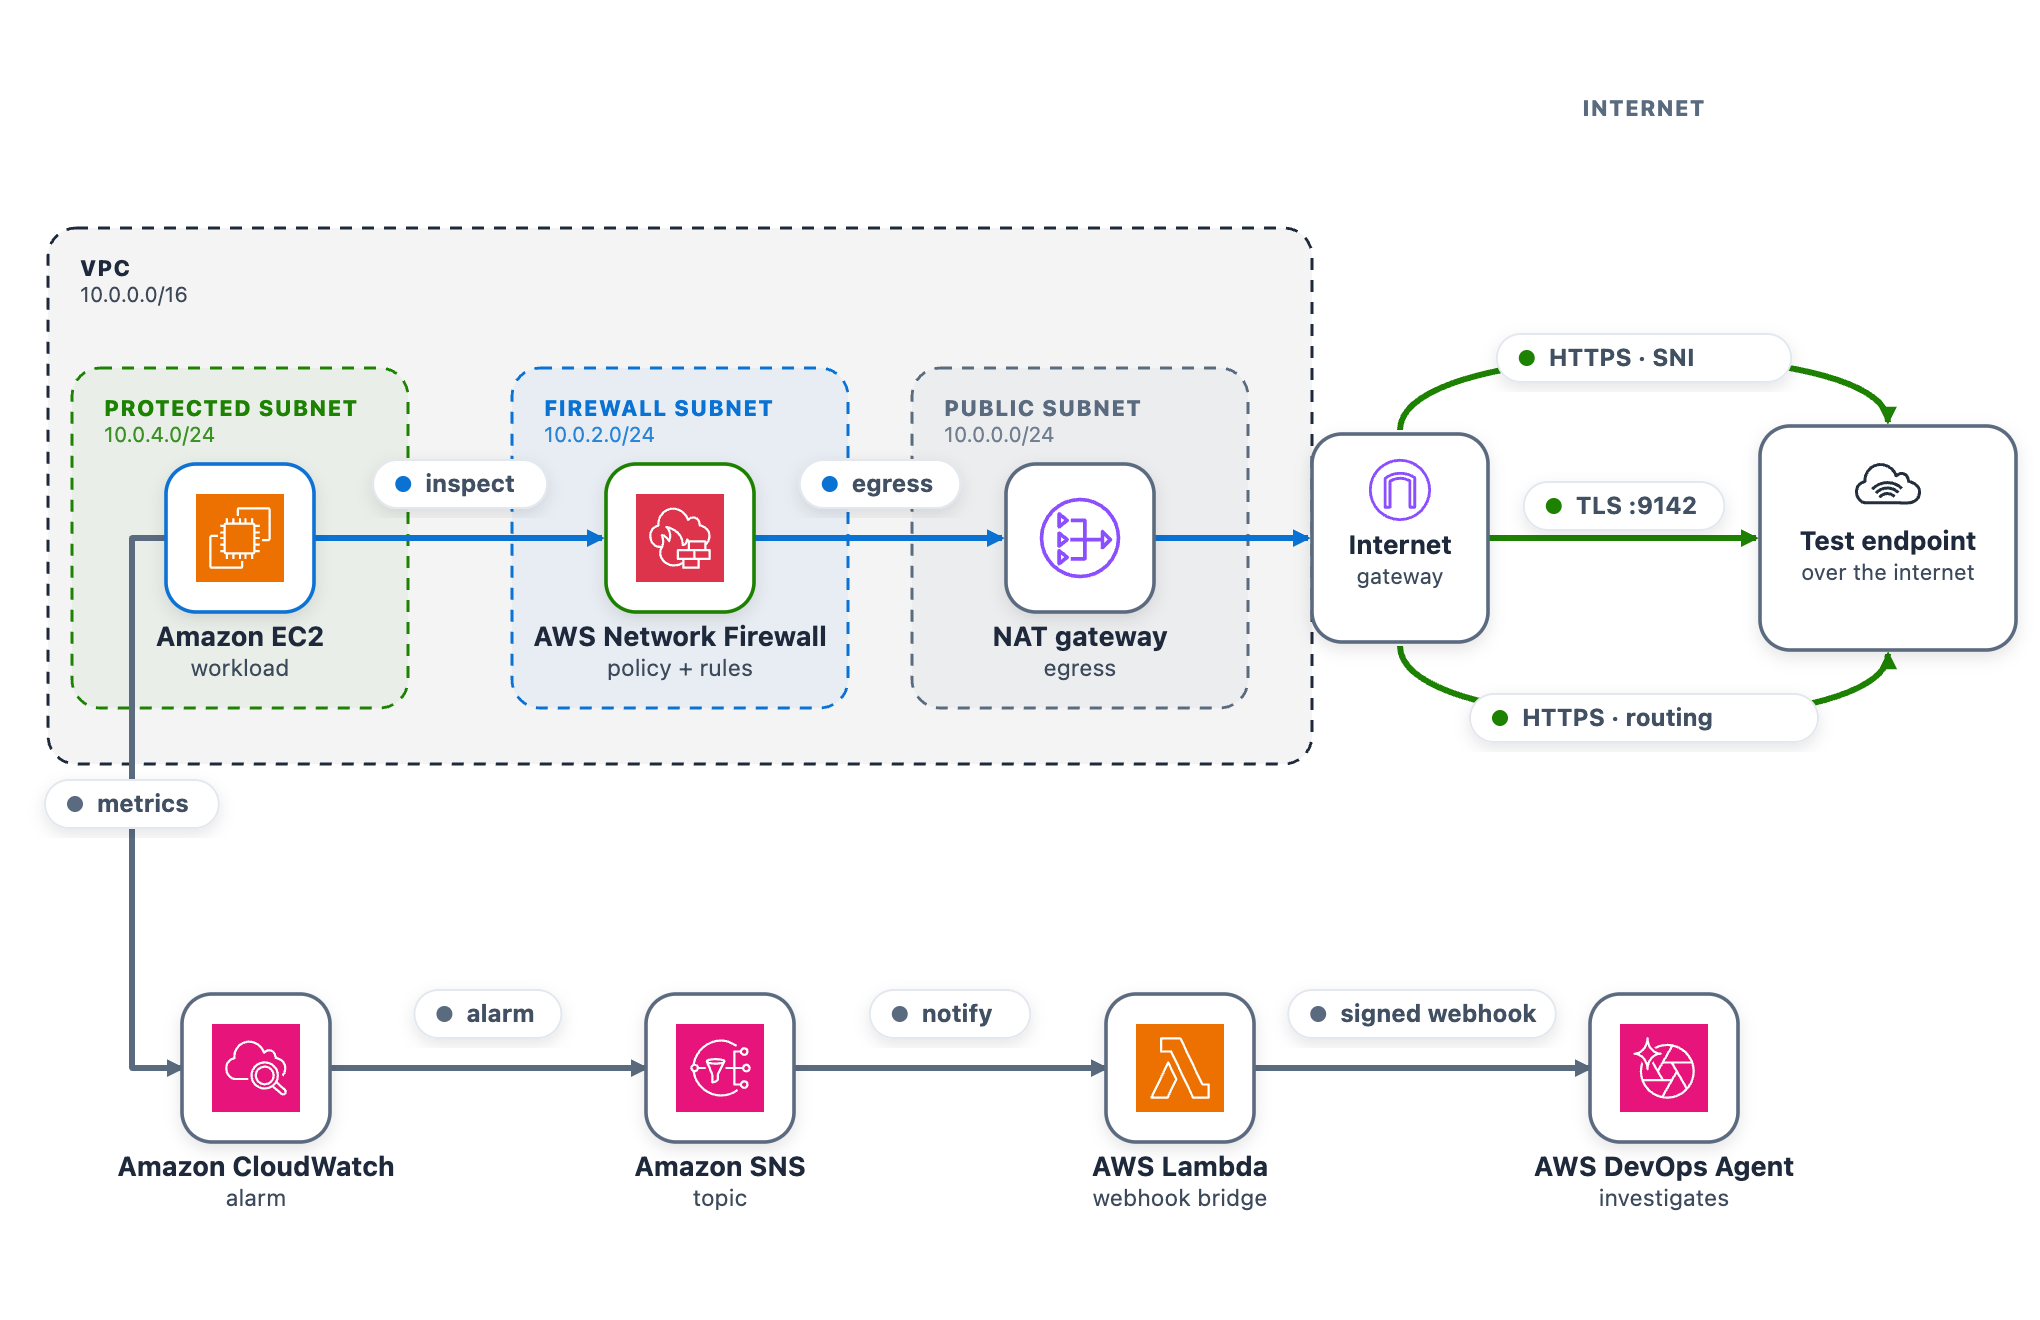
Figure 1: The sample workload

Figure 1: The sample workload

To use this with your own workload, you need a CloudWatch alarm that detects the connectivity problem and the webhook pipeline (SNS topic and Lambda function) that delivers it to DevOps Agent. The agent reads your firewall configuration, logs, and CloudTrail through AWS APIs, so no additional instrumentation is needed on the firewall side.

Prerequisites

To follow along with this post, you need:

Deploy the sample workload

Clone the project and deploy it into us-east-1 with one command (set awsRegion to use another AWS Region).

git clone https://github.com/aws-samples/sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent.git
cd sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent
bash scripts/deploy.sh

The script checks prerequisites, installs dependencies, compiles and tests, and bootstraps the CDK if needed. It then deploys all the stacks from a clean baseline and prints the outputs, including the status-page URL and sign-in details.

  1. Open the status-page link (an https://<random-id>.cloudfront.net address).
  2. Sign in using the username and password provided from the CDK output and confirm all three cards show the green Healthy status.
  3. Keep the page open while you run the scenarios.

Connect AWS DevOps Agent

To connect AWS DevOps Agent to the alarm pipeline

  1. In the AWS DevOps Agent console, open the nf-devops-agent-space Agent Space created by the CDK deployment.
  2. Configure the DevOps Agent webhook and download the CSV file with the webhook URL and signing secret.
  3. On the status page, choose Configure webhook, paste the URL and signing secret, and save. The page writes them to the nf-devops-agent-webhook-credentials AWS Secrets Manager secret, so there is no AWS CLI or console step. Until you set it, the bridge Lambda function sees a placeholder and skips delivery.
  4. Verify the path before you run a scenario. In the Lambda console, open nf-devops-agent-webhook and use the Test tab with this event.
    {
      "Records": [
        {
          "Sns": {
            "Message": "{\"AlarmName\":\"TEST-webhook-verification\",\"AlarmDescription\":\"[TEST] Webhook integration test - not a real alarm.\",\"NewStateValue\":\"ALARM\",\"NewStateReason\":\"[TEST] Manual webhook connectivity test. Safe to ignore.\",\"Region\":\"us-east-1\"}"
          }
        }
      ]
    }

  5. A 200 response confirms the path, and a test investigation appears in the DevOps Agent Operator Web App view.

How the alarm pipeline works

Every scenario reaches DevOps Agent the same way. A CloudWatch alarm moves to ALARM and notifies the SNS topic. Amazon SNS invokes a Lambda function. The function reads the webhook URL and signing secret from Secrets Manager, signs an alarm payload, and POSTs it to the DevOps Agent webhook (as shown in Figure 1). Amazon SNS also provides delivery retries, fan-out to other subscribers, and cross-account publishing.

  • Prebuilt Network Firewall metric (Scenario 1) Alarm-1 watches the DroppedPackets metric, summed across the stateful streams, and triggers when drops rise above a baseline threshold. This requires no workload or custom metric and works on an already-deployed firewall. However, it only tells you that the firewall is dropping packets, not which rule is responsible.
  • Application health metric (Scenarios 2 and 3) Alarm-2 and Alarm-3 watch a custom metric from a connectivity check. Use this for an alarm tied to user-facing impact or to tell one traffic path from another, which requires running a component that emits the metric.
Alarm Source Triggers when
Alarm-1 Native AWS/NetworkFirewall DroppedPackets The firewall’s dropped-packet count rises above the baseline
Alarm-2 Custom application health metric The port 9142 (TCP) connectivity check to the test endpoint is being dropped
Alarm-3 Custom application health metric The cross Availability Zone connectivity check is being dropped

Run the scenarios

Work through each of the scenarios one at a time, following the same cycle. Interrupt network connectivity, watch the alarm trigger, let DevOps Agent investigate, apply the recommended fix, and confirm recovery before moving on.

The status-page cards follow the live CloudWatch alarm state. A card shows a green dot and the word Healthy when its alarm is clear, and a red dot and the word DROPPED when its alarm triggers. In the DROPPED state the card also adds a Condition: line describing what’s being dropped, which isn’t shown when the card is healthy. Network Firewall applies changes to new flows, so a change shows within a minute or two. Recovery comes from the mitigation DevOps Agent recommends, which you review and apply.

Scenario 1. Domain deny list blocking a legitimate endpoint

At baseline, the rg-domain Suricata domain rule group denies only an unused placeholder, so the test endpoint stays reachable. The rule group inspects the TLS Server Name Indication (SNI) on each outbound connection and drops any that matches a denied domain. The exact rule syntax and console steps follow.

To add the domain deny rule

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-domain rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. The rules box already contains two baseline placeholder rules (they match blocked.placeholder.invalid, so nothing real is denied). Leave those in place. Find the <app-endpoint-dns> value for Scenario 1 in the deployment script output (a Nework Load Balancer (NLB) DNS name such as NfTest-AppNl-a1b2C3dEf4G5-1234abcd5678efgh.elb.us-east-1.amazonaws.com). On a new line below the existing rules, add a drop rule that matches that DNS name on the TLS SNI, then choose Save.
    drop tls $HOME_NET any -> $EXTERNAL_NET any (ssl_state:client_hello; tls.sni; content:"<app-endpoint-dns>"; startswith; nocase; endswith; msg:"S1 domain denylist"; flow:to_server, established; sid:2000002; rev:1;)

  6. After saving, the rules box holds all three lines. The two placeholders remain, plus the new drop rule for the endpoint DNS name (note the distinct sid 2000002).
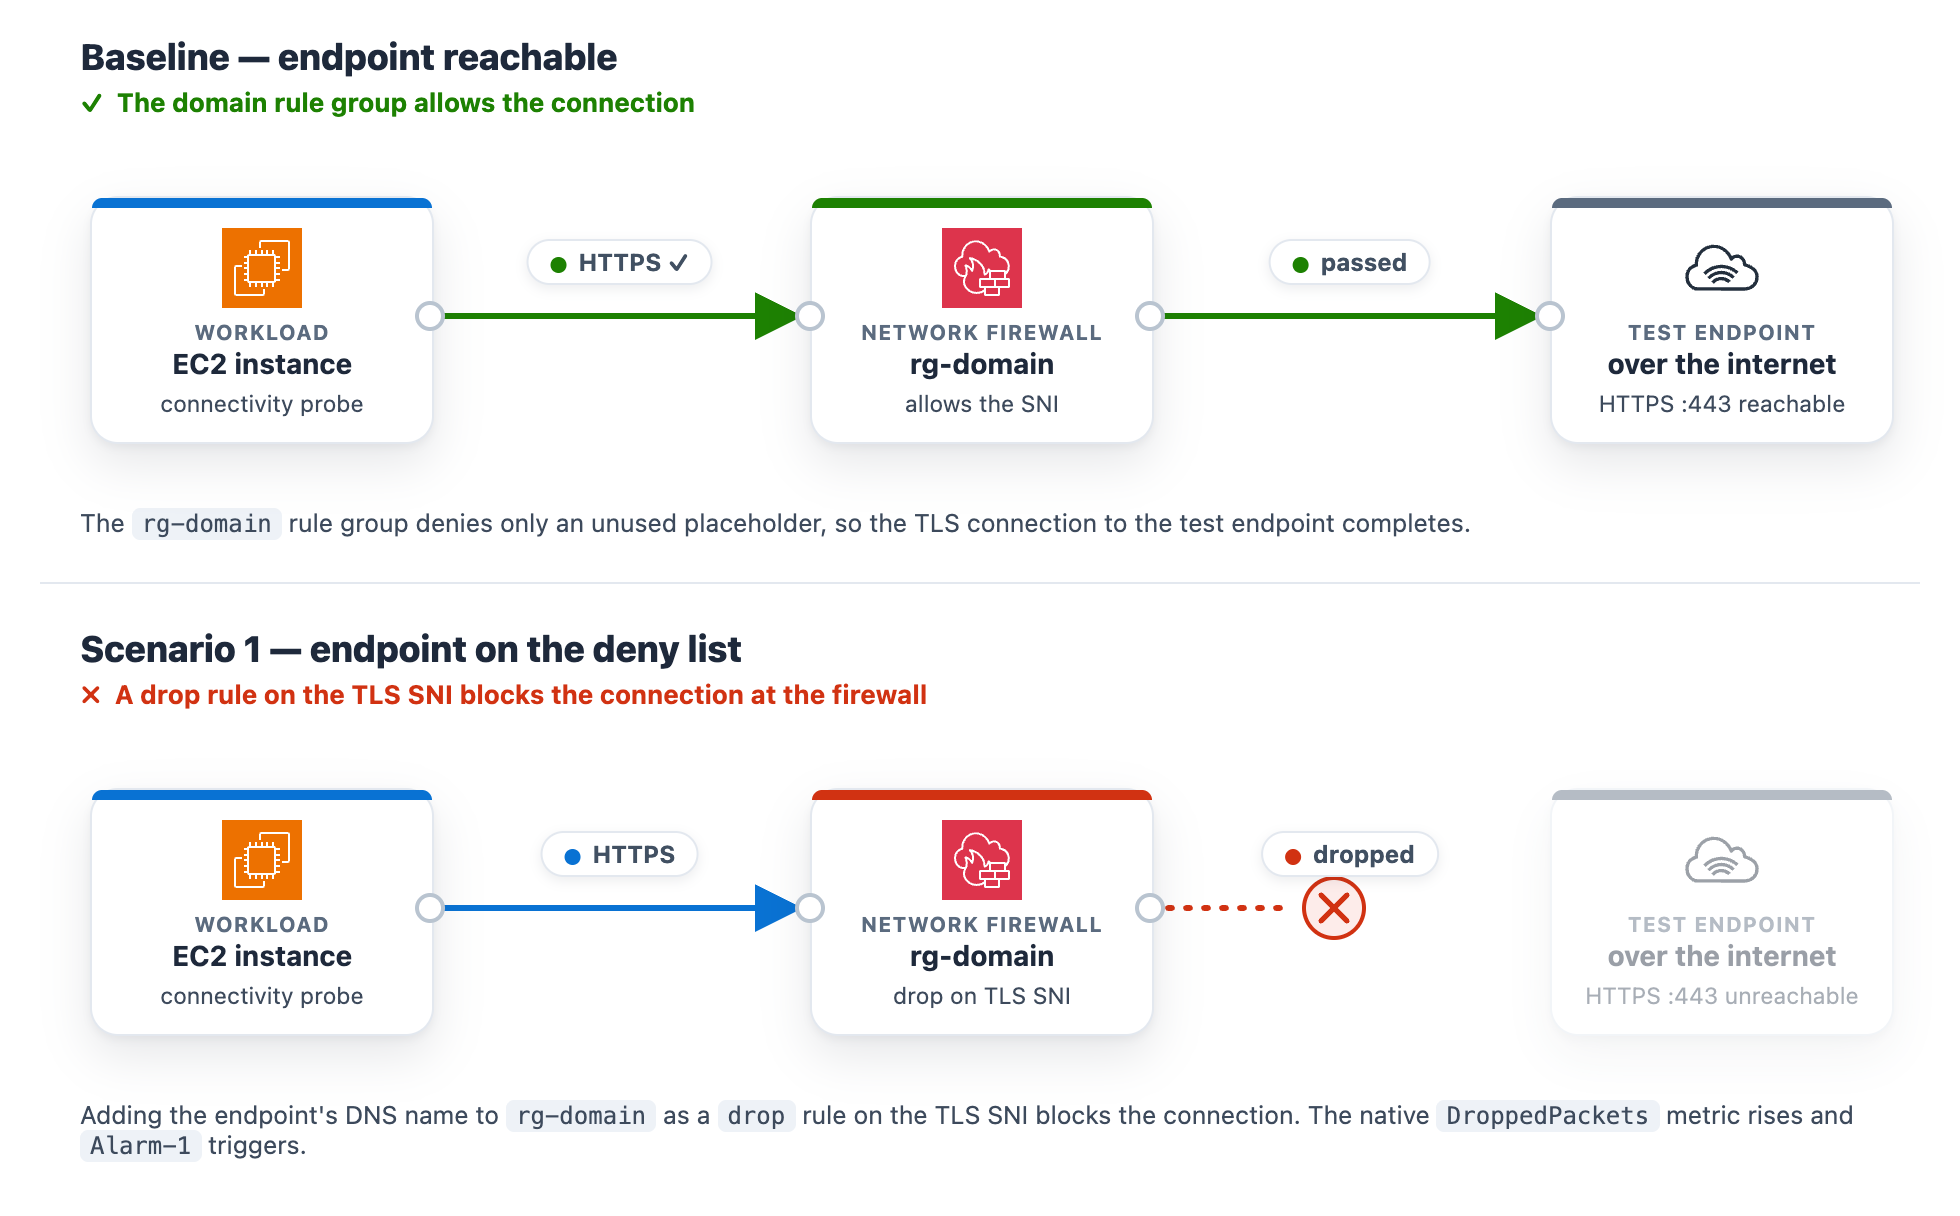
Figure 2: Scenario 1 – Firewall rule change blocking the connection

Figure 2: Scenario 1 – Firewall rule change blocking the connection

What happens. The workload’s HTTPS check to the test endpoint times out, the “AWS/NetworkFirewall DroppedPackets metric climbs above baseline, and Alarm-1 moves to ALARM. The Scenario 1 card reads DROPPED (with the condition Firewall dropping the monitored domain on its allow/deny rules), while the Scenario 2 and Scenario 3 cards stay Healthy (Figure 3). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the HTTPS · SNI line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).
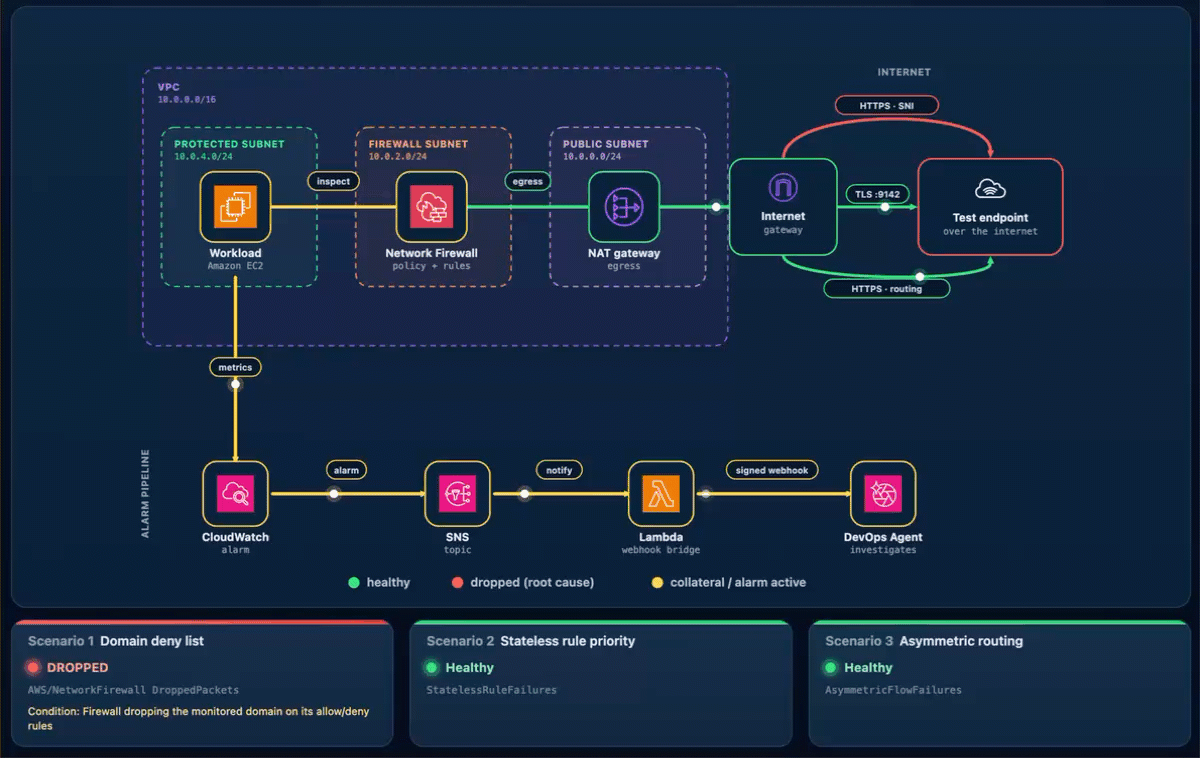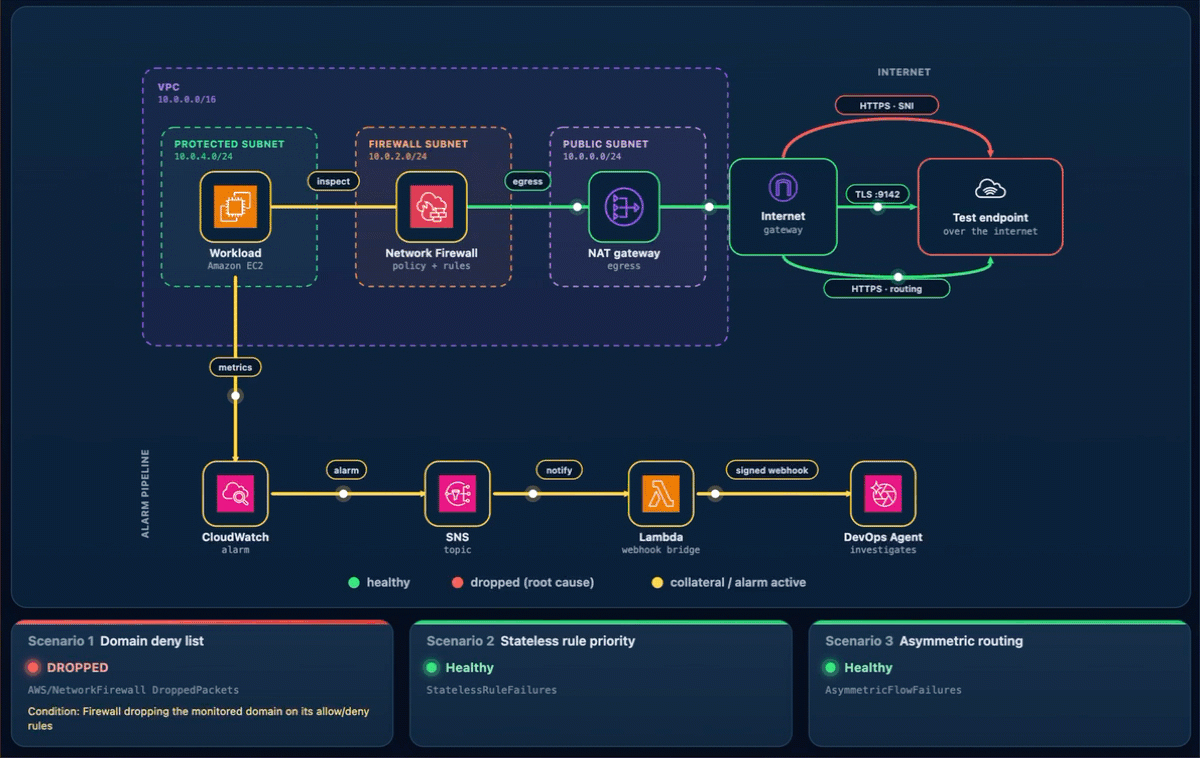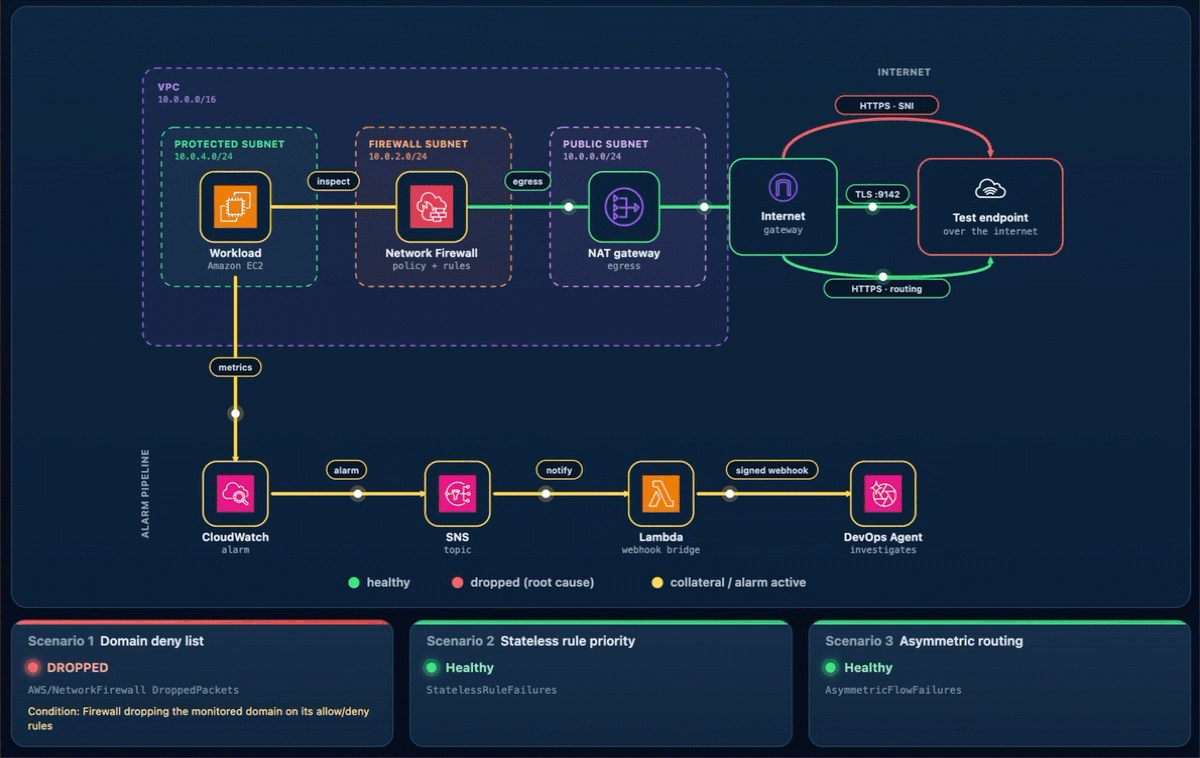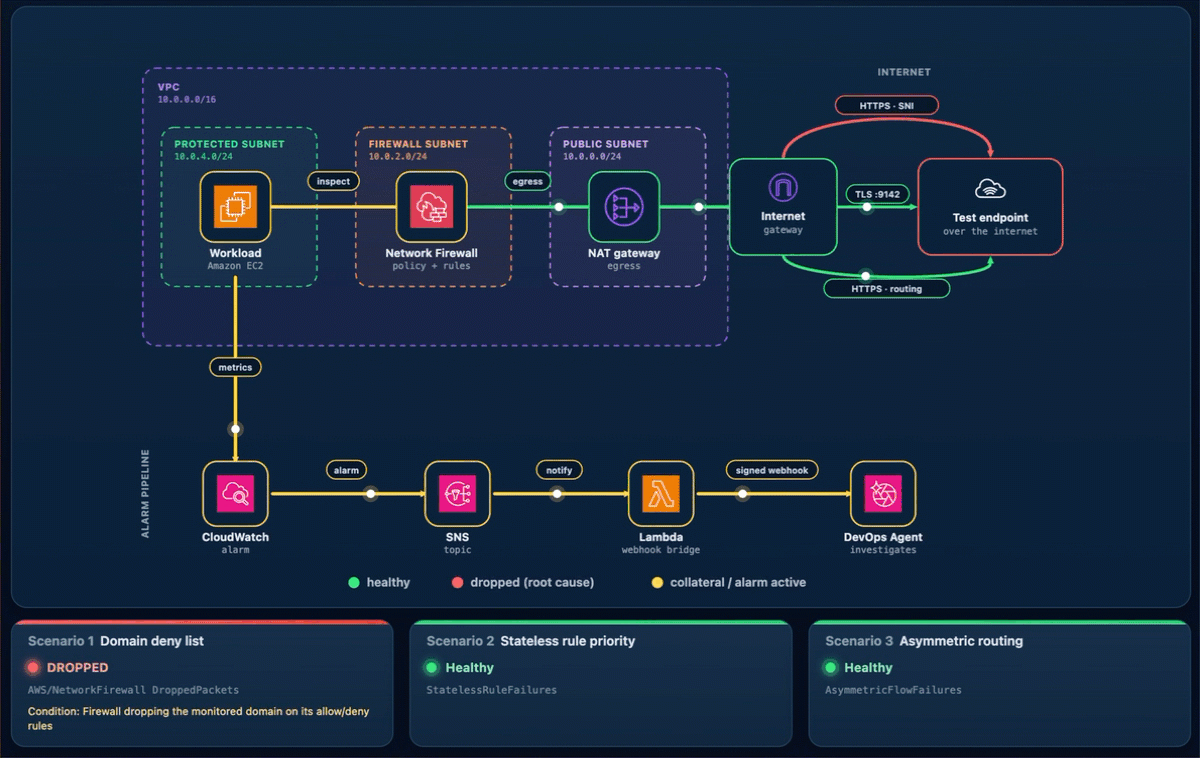
Figure 3: Scenario 1 active – Traffic blocked at the firewall

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Let DevOps Agent investigate. The agent runs several lines of investigation in parallel and correlates them:

  1. Reads the DroppedPackets metric and correlates the spike with a simultaneous drop in passed packets, confirming the firewall is actively blocking traffic.
  2. Reads the ALERT log and finds the workload’s TLS connections to the test endpoint blocked by the S1 domain denylist rule.
  3. Compares the current state against a baseline window, where the same endpoint was reachable with no alerts, which shows the block is new.
  4. Searches CloudTrail and surfaces the UpdateRuleGroup call that added the deny rule, identifying the user, role, and timestamp approximately one minute before the drops began.
  5. Reports the root cause as that manual rule-group change. Recommends removing the deny entry or adding an allow exception and enabling FirewallPolicyChangeProtection to prevent unauthorized changes.
  6. Presents this as a plan you review and apply, not an automatic change.

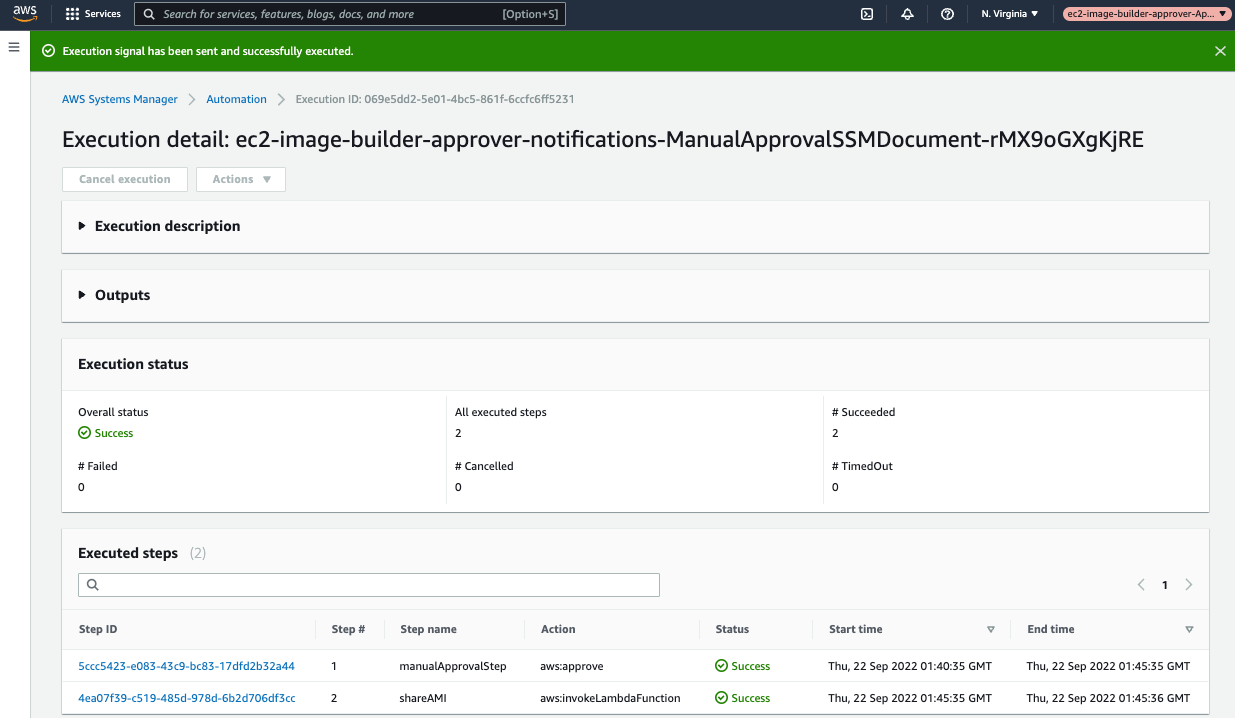
In the DevOps Agent Operator Web App view, the agent first restates the Alarm-1 trigger and confirms the firewall is dropping packets above the threshold (Figure 4).
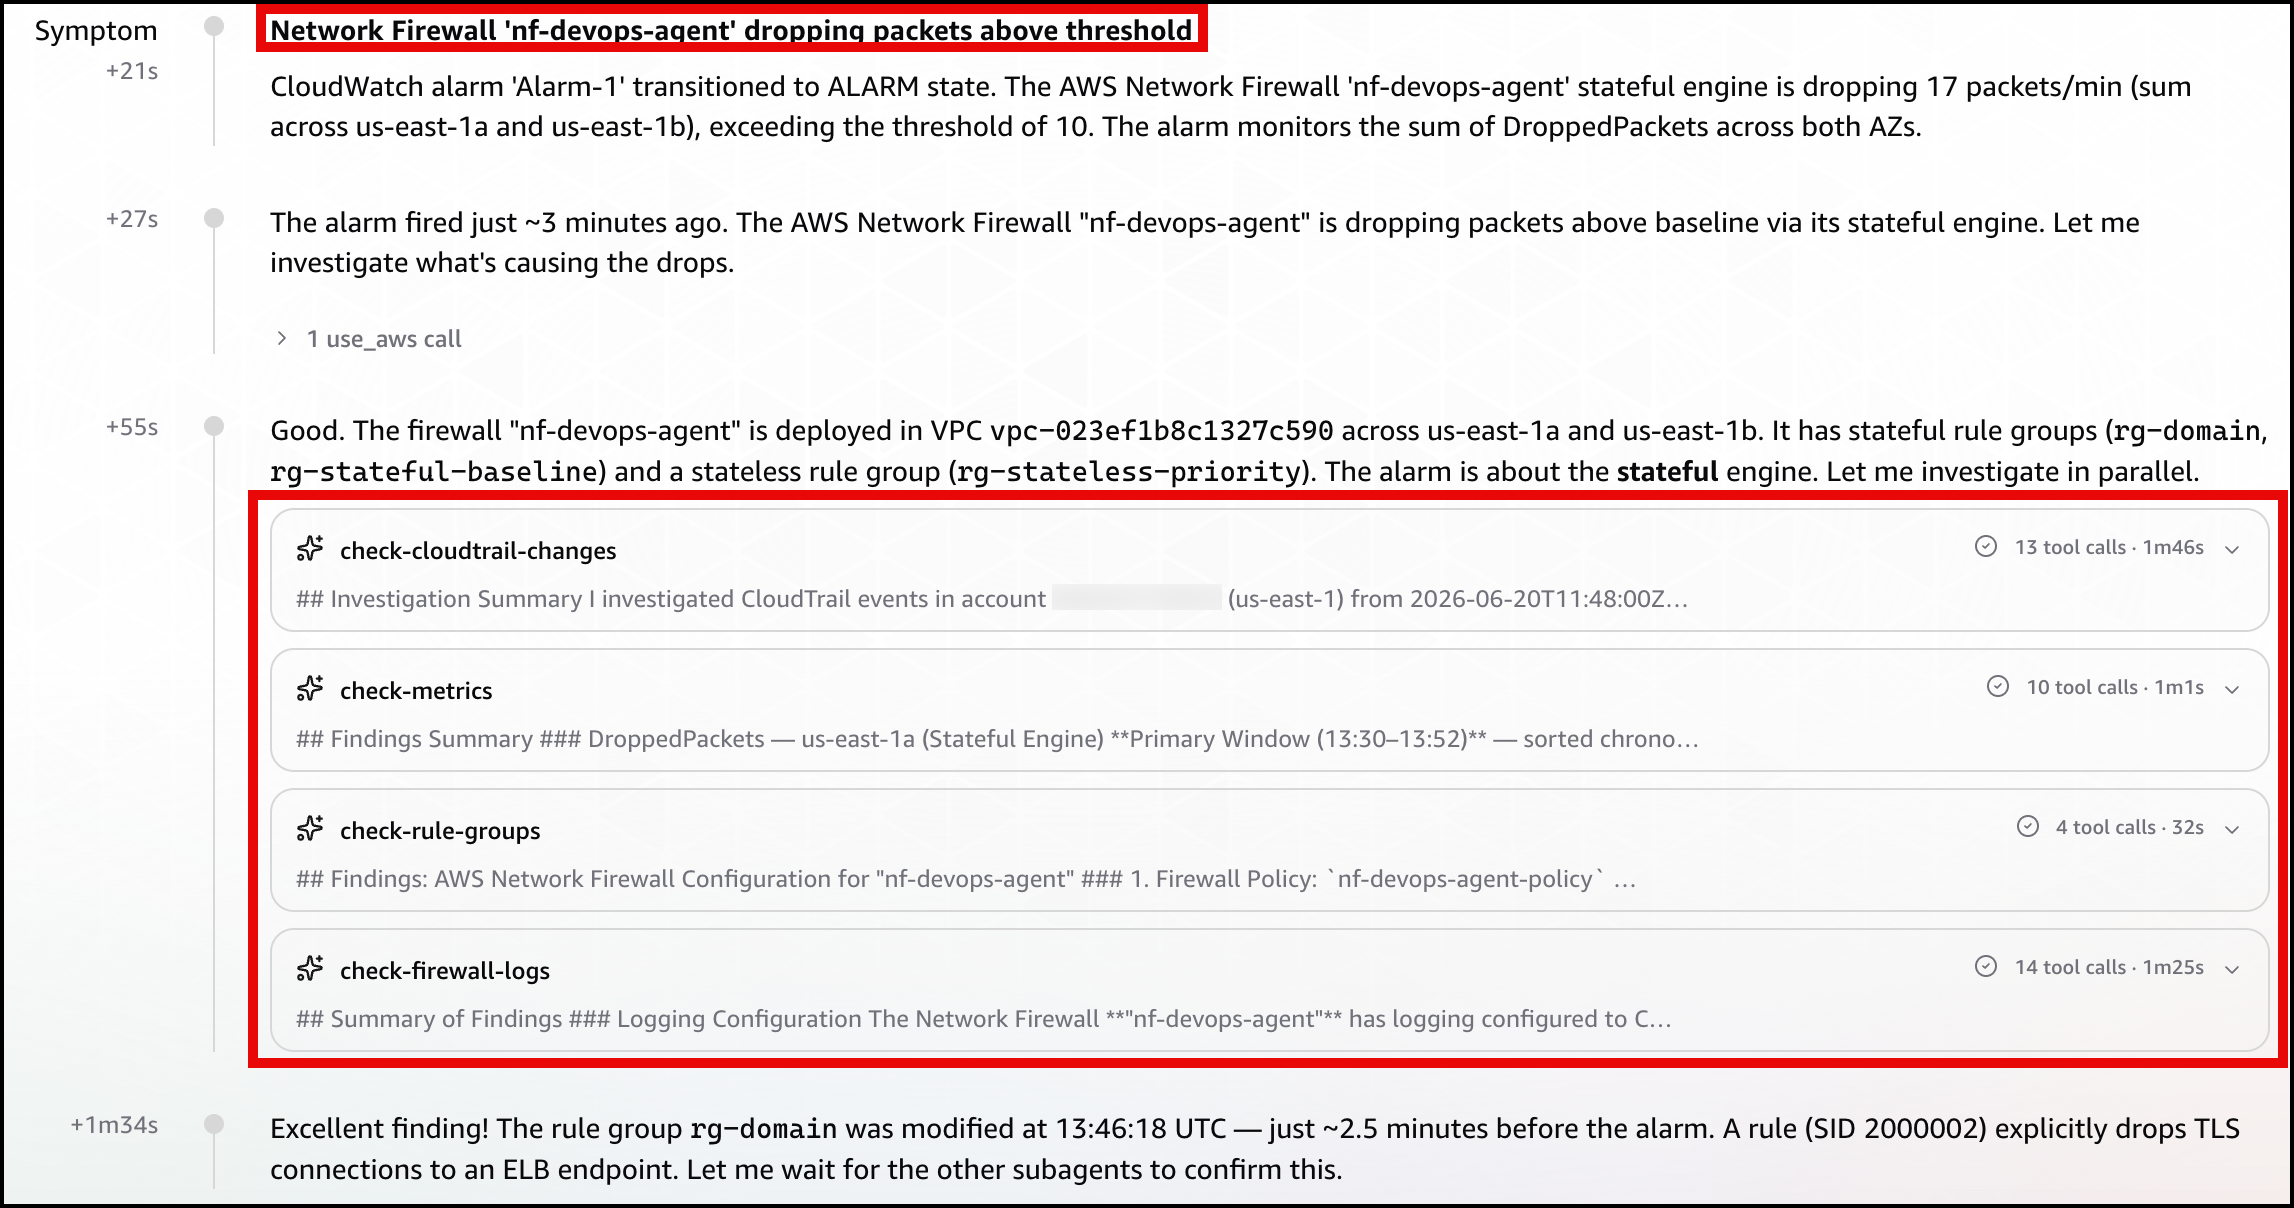
Figure 4: Scenario 1 – The symptom

Figure 4: Scenario 1 – The symptom

Next, the agent identifies the root cause: a manual update to the rg-domain rule group that added a domain deny rule (SID 2000002) shortly before the alarm fired, blocking TLS connections to the ELB endpoint (Figure 5).
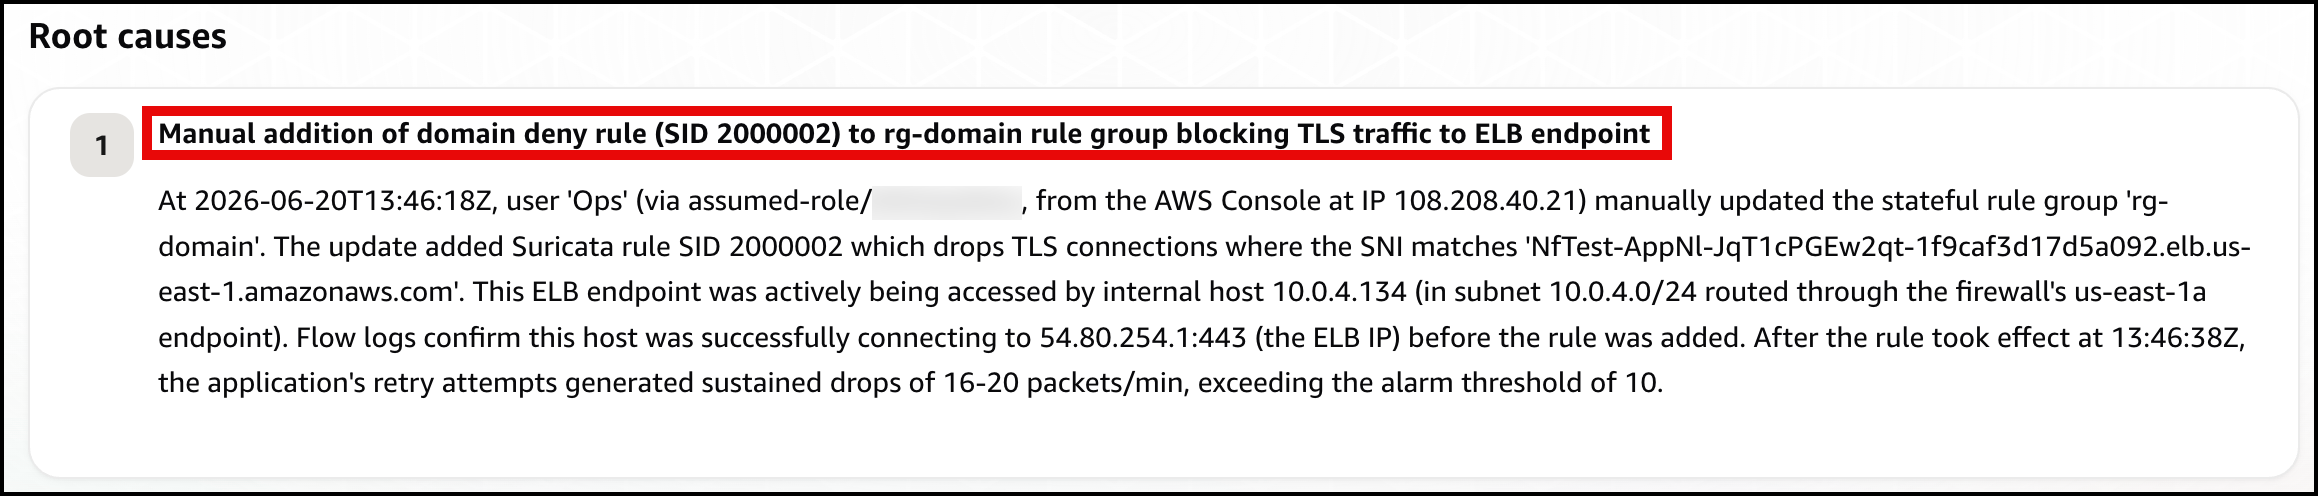
Figure 5: Scenario 1 – The root cause

Figure 5: Scenario 1 – The root cause

Finally, the agent presents a mitigation plan, recommending you remove the problematic deny rule (SID 2000002) to restore connectivity (Figure 6).
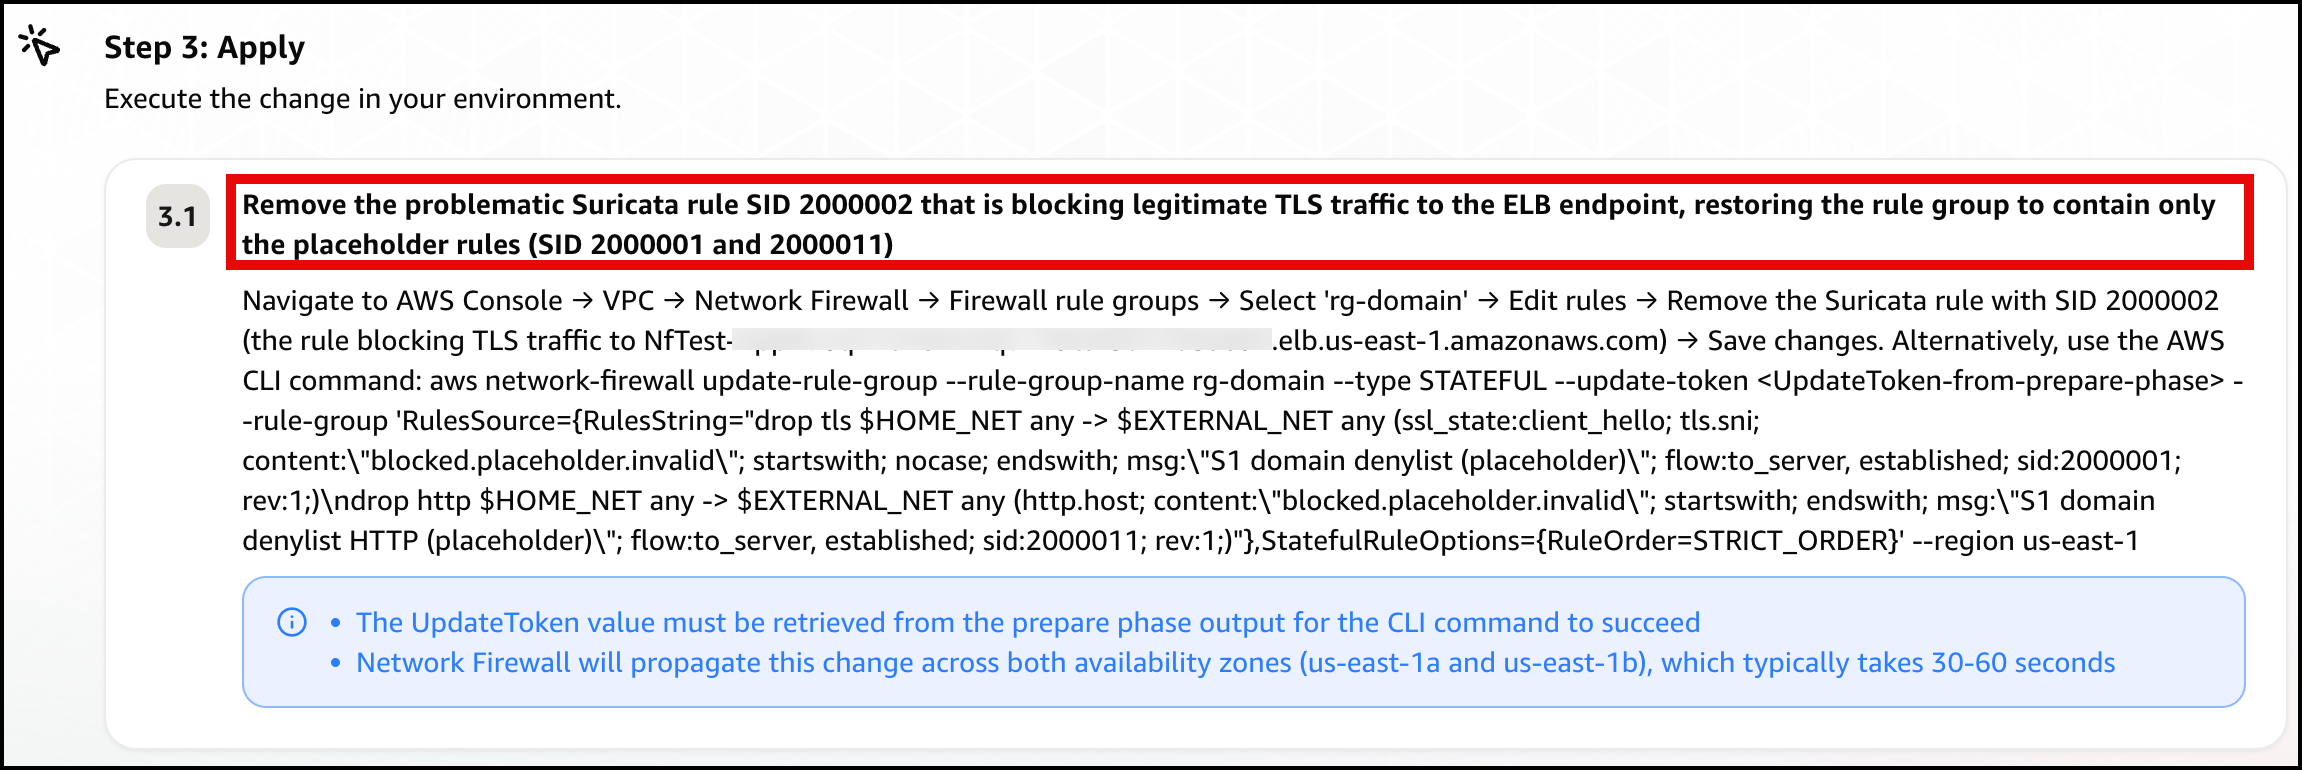
Figure 6: Scenario 1 – The mitigation plan

Figure 6: Scenario 1 – The mitigation plan

Note: In a real-world environment, this type of rule typically exists for a reason. Before removing it, verify whether it was intentional but scoped too broadly. If so, refine the rule to block only unauthorized endpoints rather than removing it entirely.

Confirm recovery. Apply the change the agent recommends. After the deny entry is gone, DroppedPackets falls back to baseline, Alarm-1 clears, and the card returns to green. Move on to Scenario 2.

Scenario 2. Stateless rule priority misconfiguration

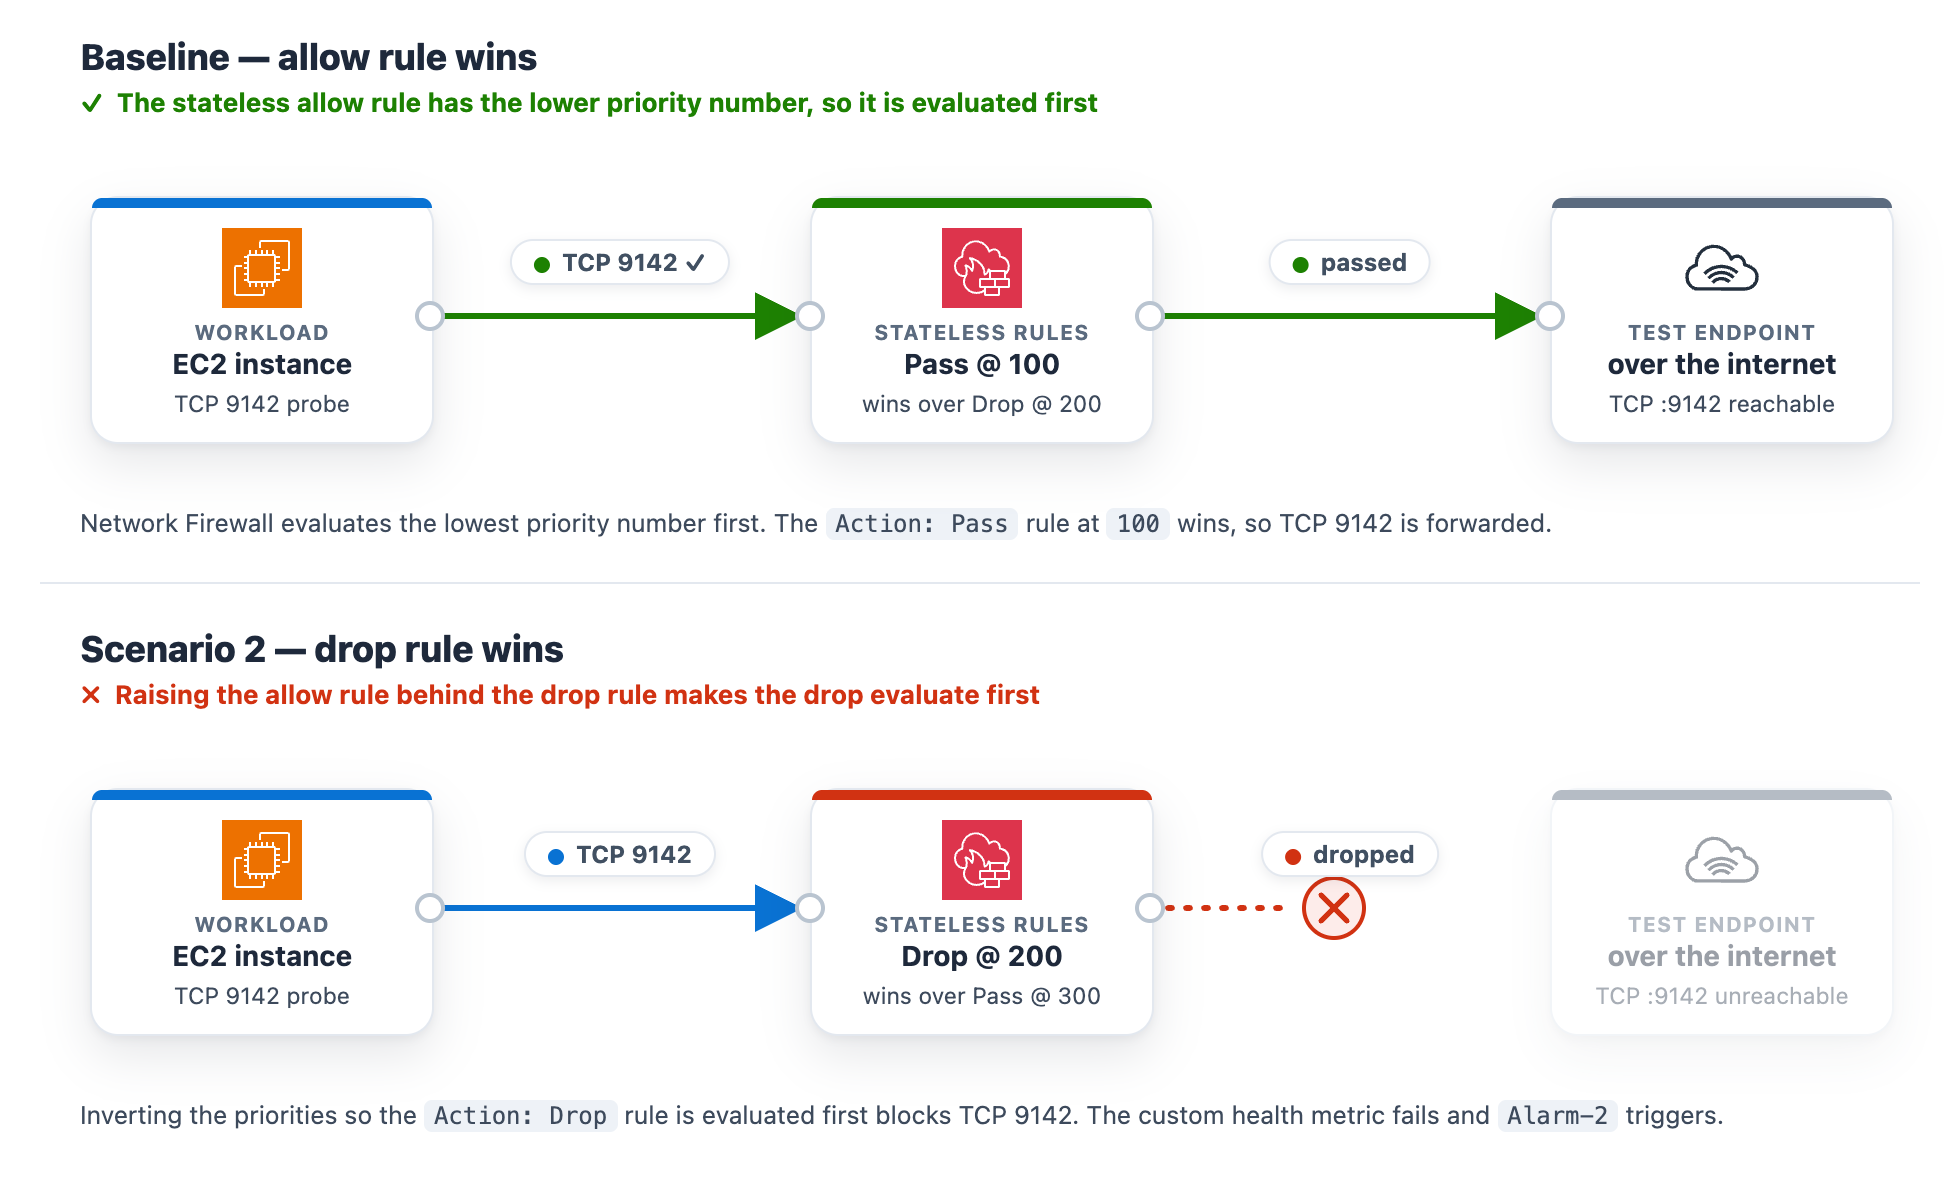
At baseline, the rg-stateless-priority stateless rule group keeps the allow rule at priority 100 and the drop rule at 200 for the test class, TCP destination port 9142. The workload opens a TCP connection to the test endpoint on this port. Lower priority numbers evaluate first, so the allow rule wins. This scenario uses port 9142 instead of 443 to demonstrate a stateless rule, which matches on the packet’s 5-tuple (protocol, ports, addresses) rather than application content.

Introduce the change. Invert the two rule priorities so the drop rule evaluates before the allow rule. This is the kind of change a rushed rule edit can introduce.

To invert the stateless rule priorities

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-stateless-priority rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. Raise the (Action: Pass) rule’s priority number so it sits after the (Action: Drop) rule, then choose Save. For example, change the (Action: Pass) rule from 100 to 300 (any number higher than the drop rule’s 200 works). You only need to move one rule, and using 300 avoids a clash with the drop rule that already sits at 200. Network Firewall evaluates the lowest priority number first, so the (Action: Drop) rule at 200 now wins for this traffic class, ahead of the (Action: Pass) rule at 300.
Figure 7: Scenario 2 – Rule priority change blocking the traffic class

Figure 7: Scenario 2 – Rule priority change blocking the traffic class

What happens. The drop rule now wins, the TCP connection to the test endpoint on port 9142 times out, the StatelessRuleFailures metric climbs above baseline, and Alarm-2 moves to ALARM. The Scenario 2 card reads DROPPED (with the condition Stateless rules dropping the monitored traffic class), while the Scenario 1 and Scenario 3 cards stay Healthy (Figure 8). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the TLS :9142 line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).
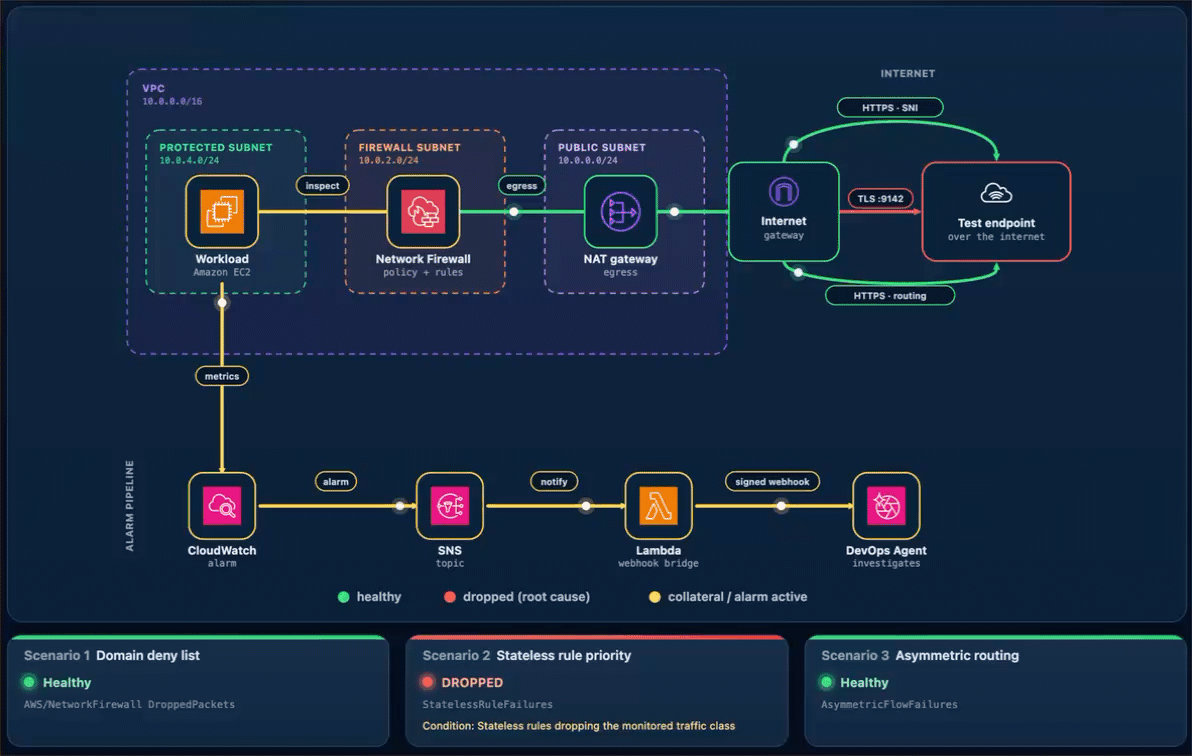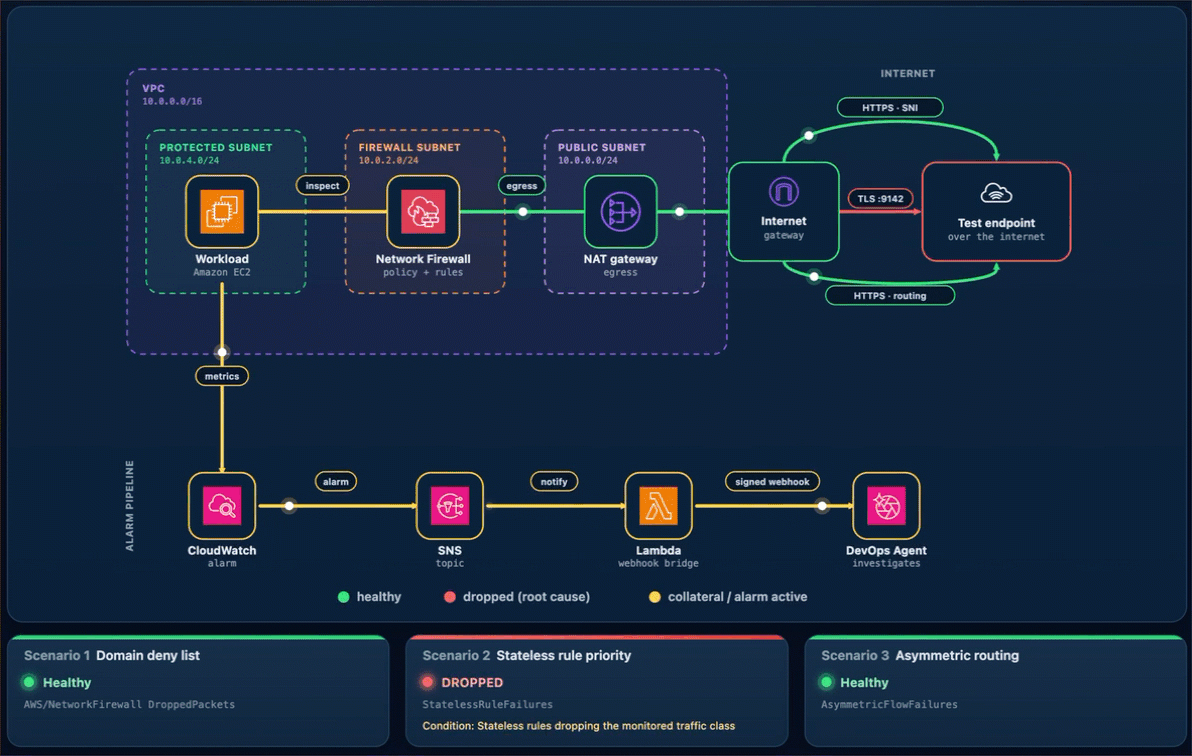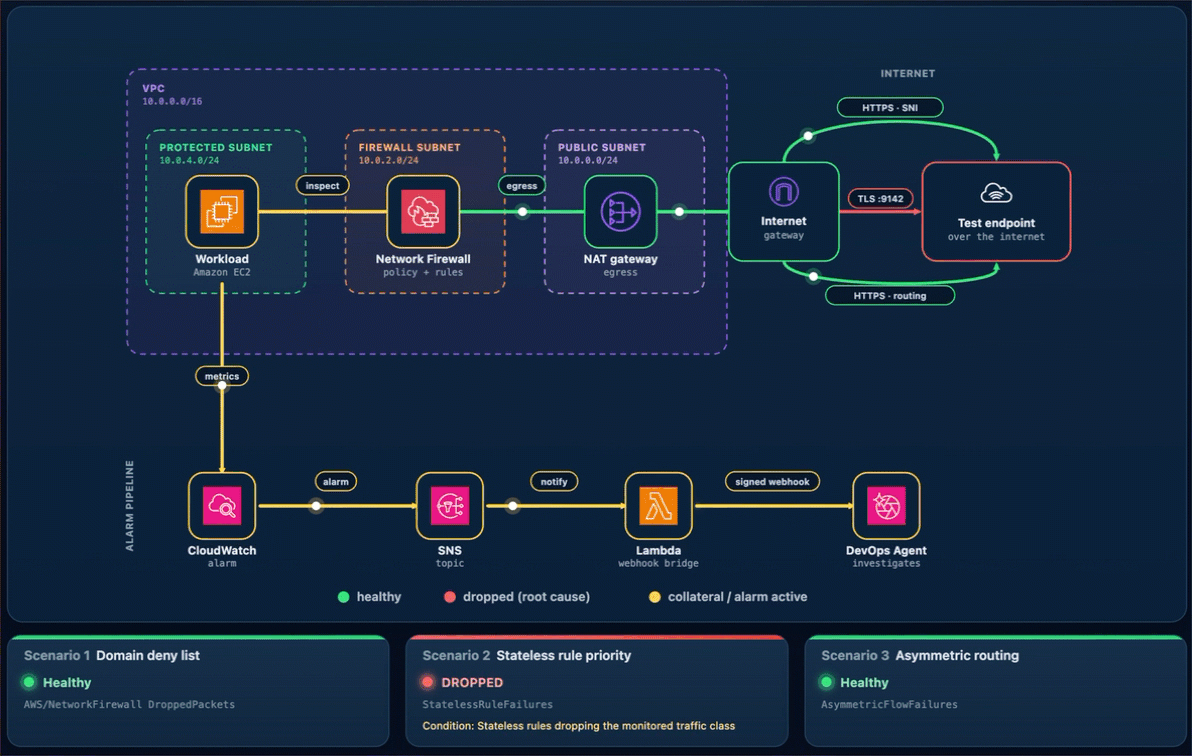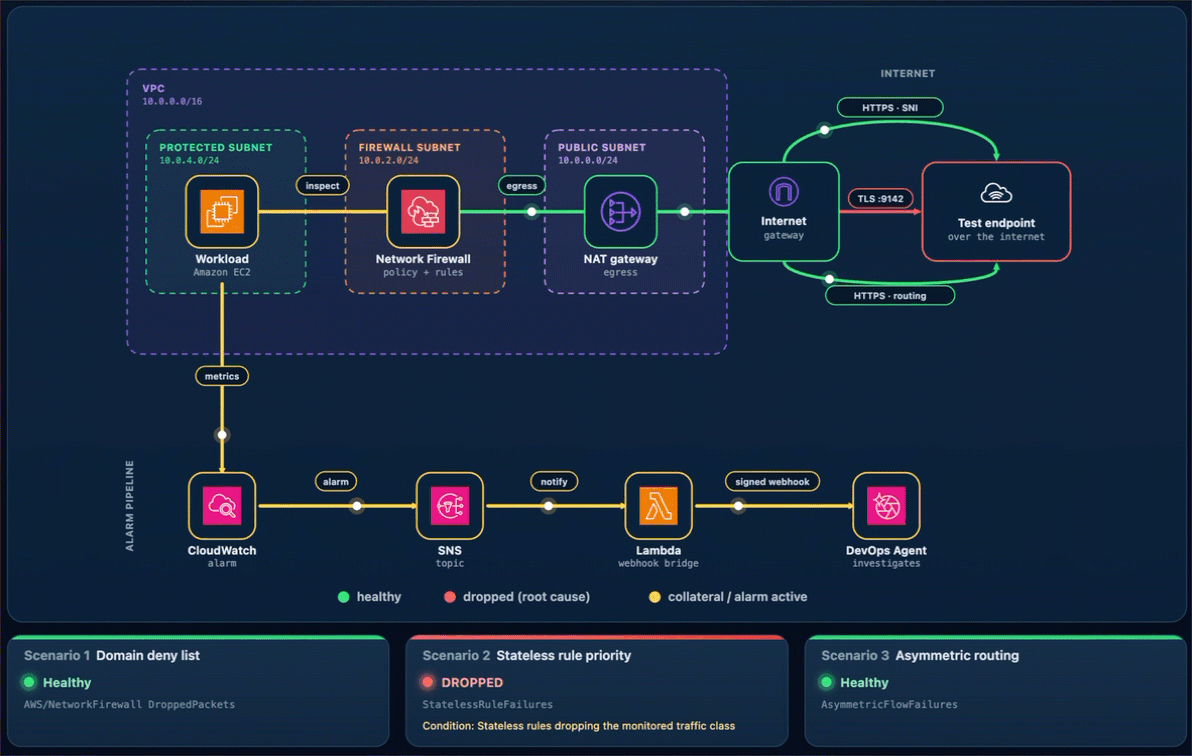
Figure 8: Scenario 2 active

Figure 8: Scenario 2 active

Let DevOps Agent investigate. A stateless drop happens before traffic reaches the stateful inspection engine, so it produces no ALERT log entries. The agent turns to configuration and flow logs instead:

  1. Reads the stateless rule group state and finds the drop rule at the lower priority number, ahead of the pass rule, so the drop evaluates first.
  2. Reads the flow logs and sees passed packets drop to zero within a minute of the change.
  3. Searches CloudTrail and surfaces the UpdateRuleGroup call that inverted the priorities, identifying the user, role, and timestamp about a minute before the alarm.
  4. Reports the root cause as that priority inversion. Recommends removing the redundant drop rule and managing the rule group through infrastructure-as-code (IaC) to prevent manual misconfigurations.
  5. Presents this as a plan you review and apply, not an automatic change.

In the DevOps Agent Operator Web App view, the agent first restates the Alarm-2 trigger and confirms that a workload connectivity health check is failing because the firewall’s stateless rules are dropping egress (Figure 9).
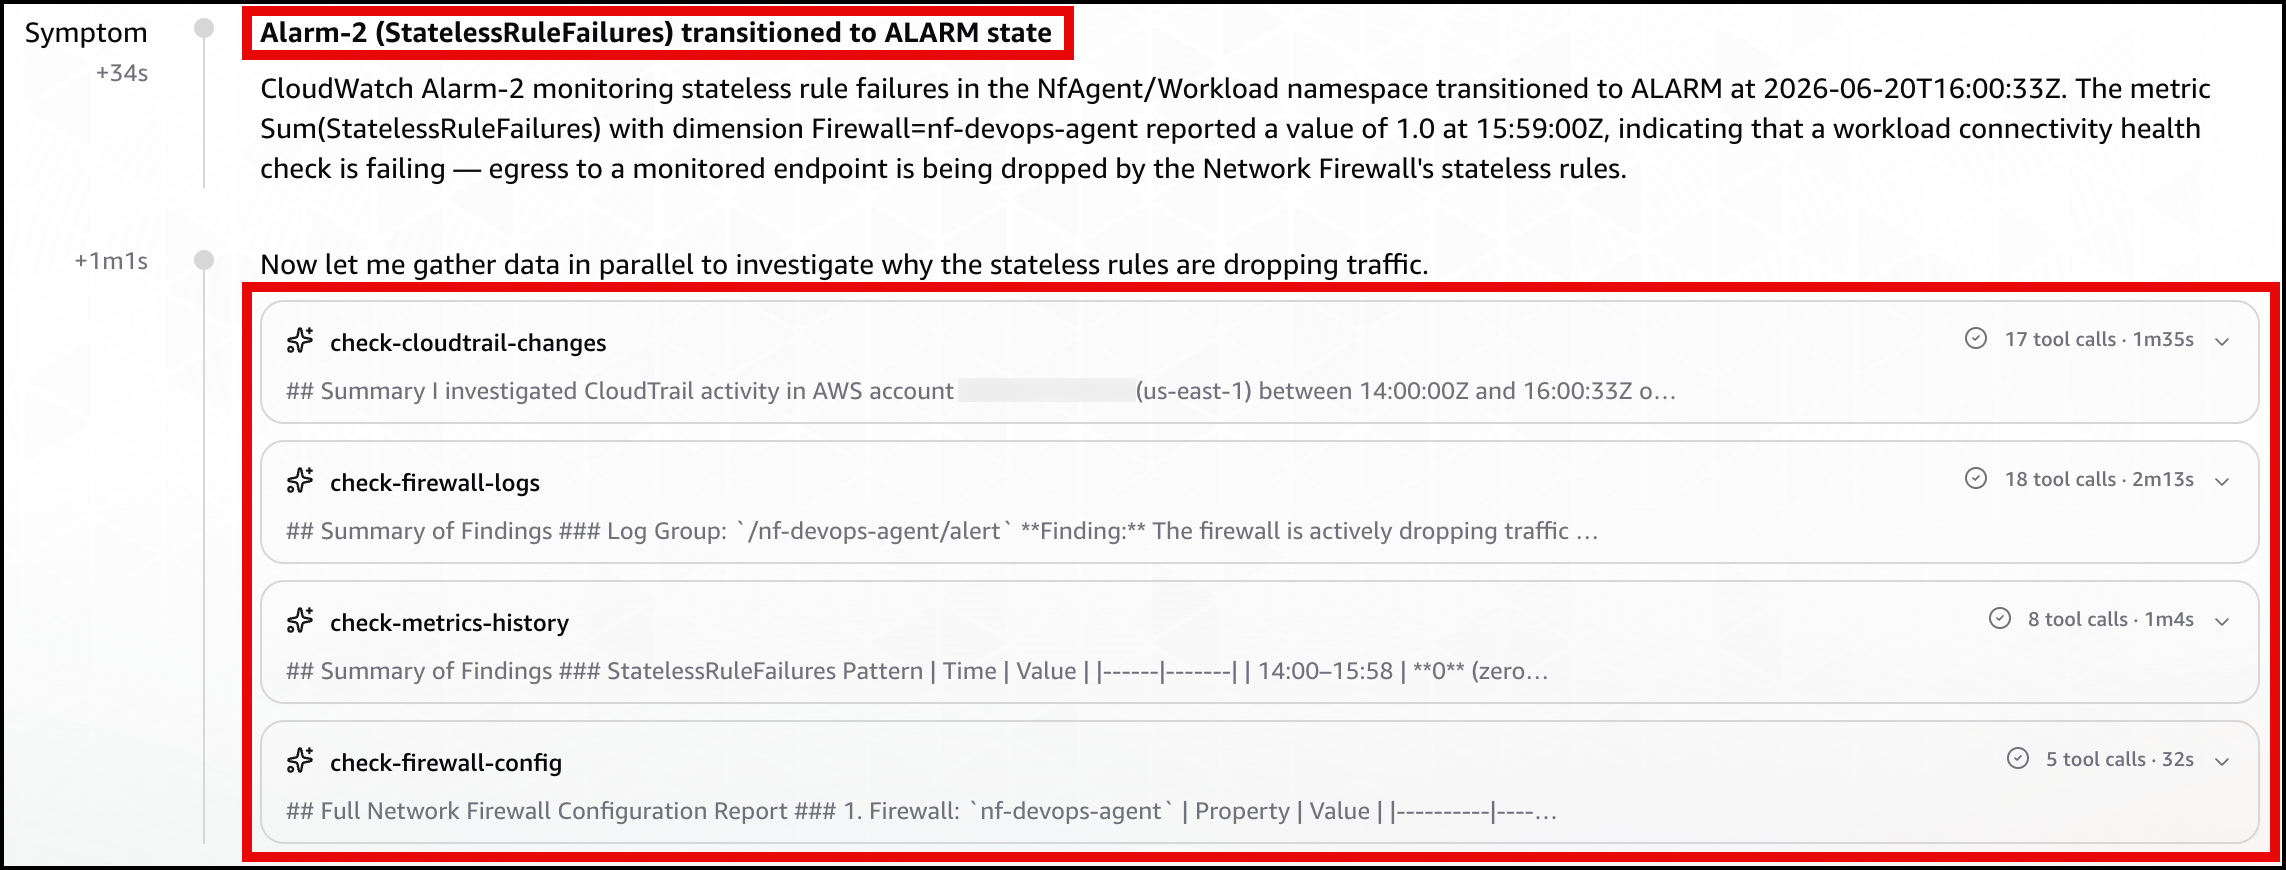
Figure 9: Scenario 2 – The symptom

Figure 9: Scenario 2 – The symptom

Next, the agent identifies the root cause, using the rule-group state and CloudTrail to pinpoint the conflicting DROP/PASS rules, where the new DROP rule’s lower priority number makes it match first (Figure 10).
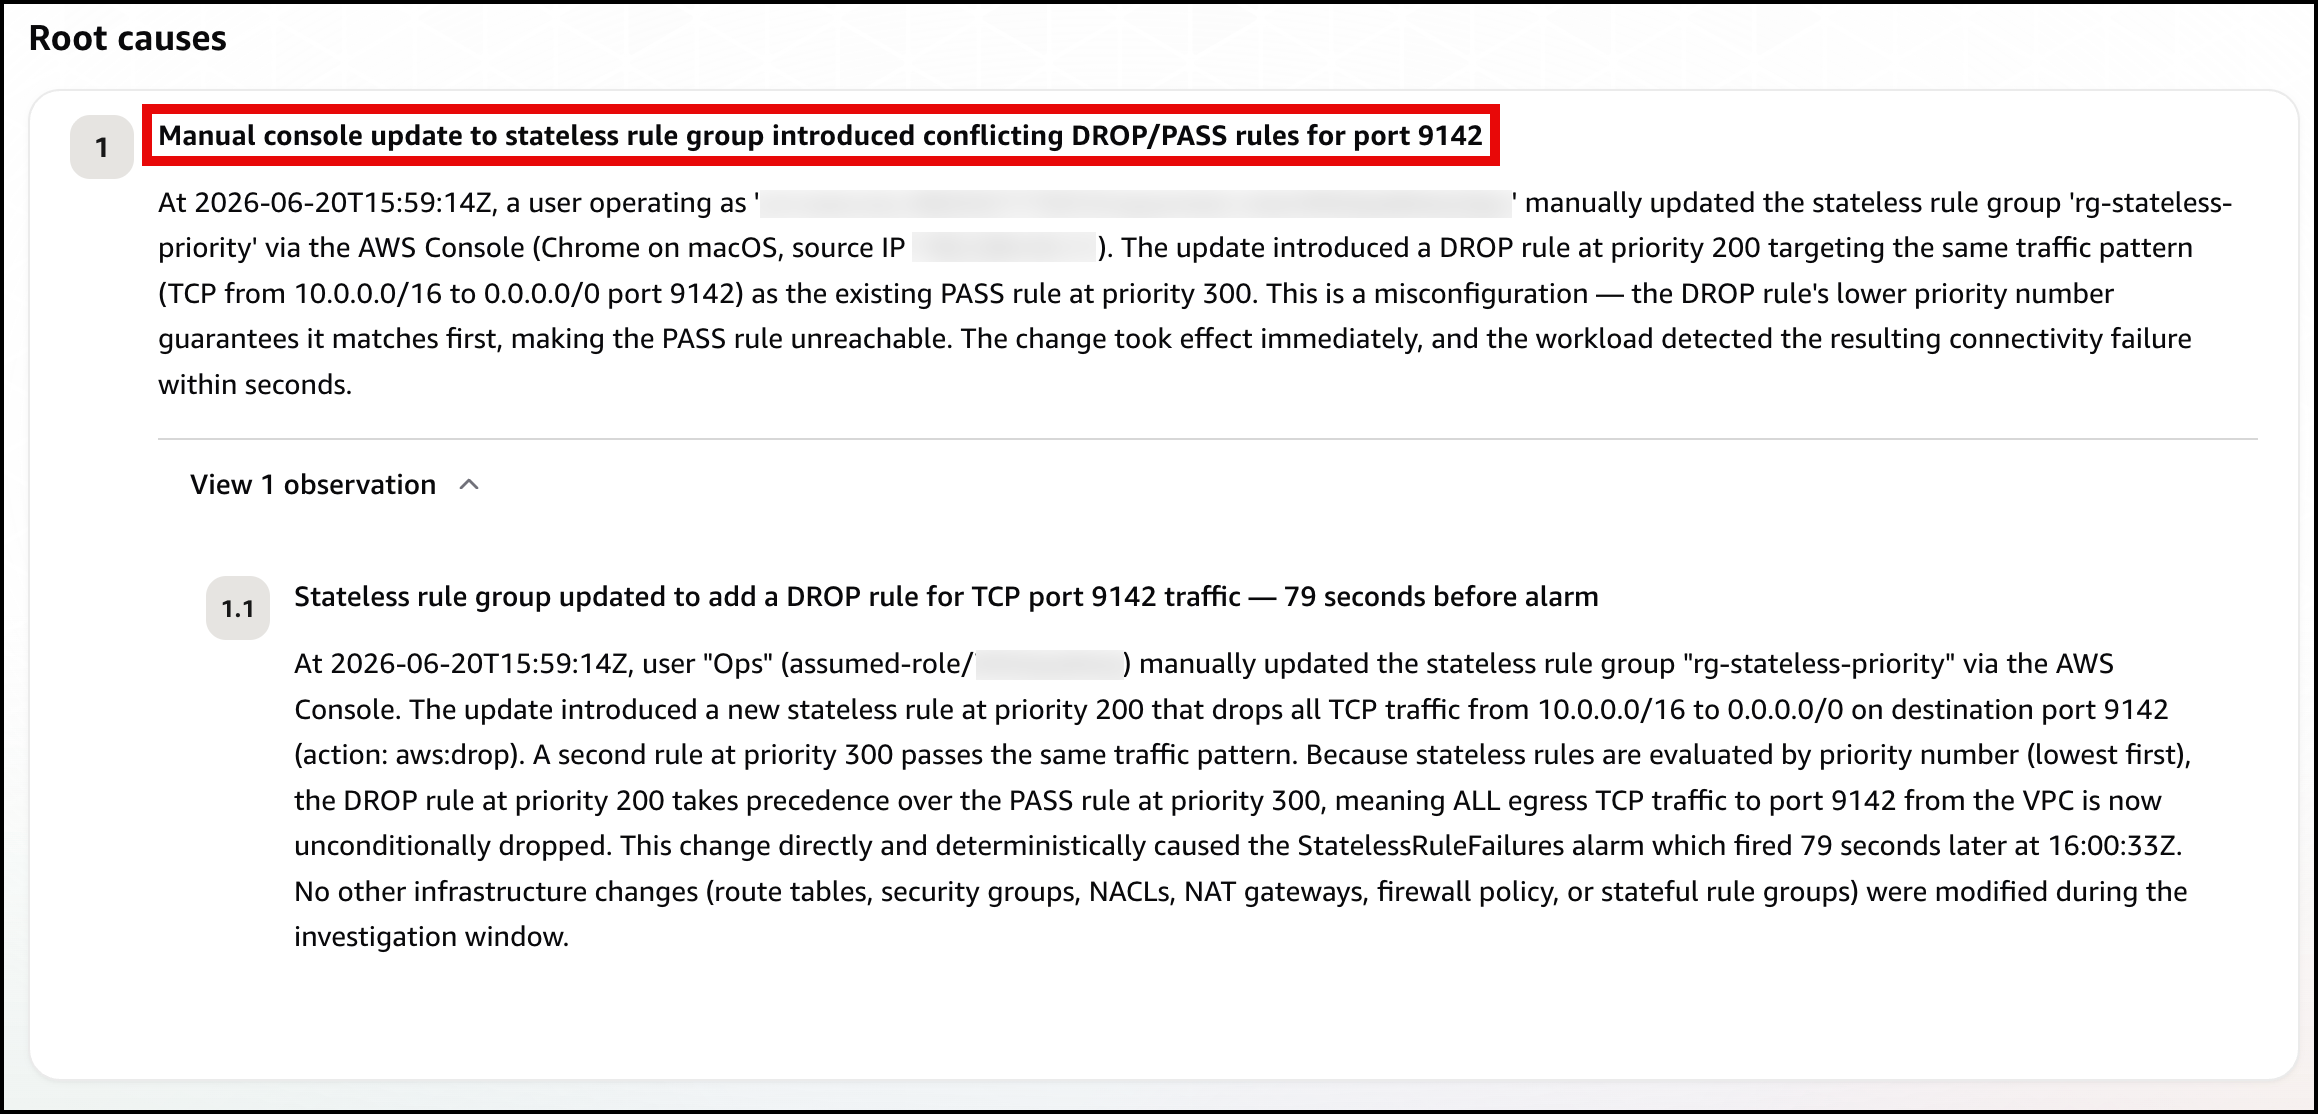
Figure 10: Scenario 2 – The root cause

Figure 10: Scenario 2 – The root cause

Finally, the agent presents a mitigation plan, recommending you remove the conflicting DROP rule at priority 200 to restore traffic flow (Figure 11).
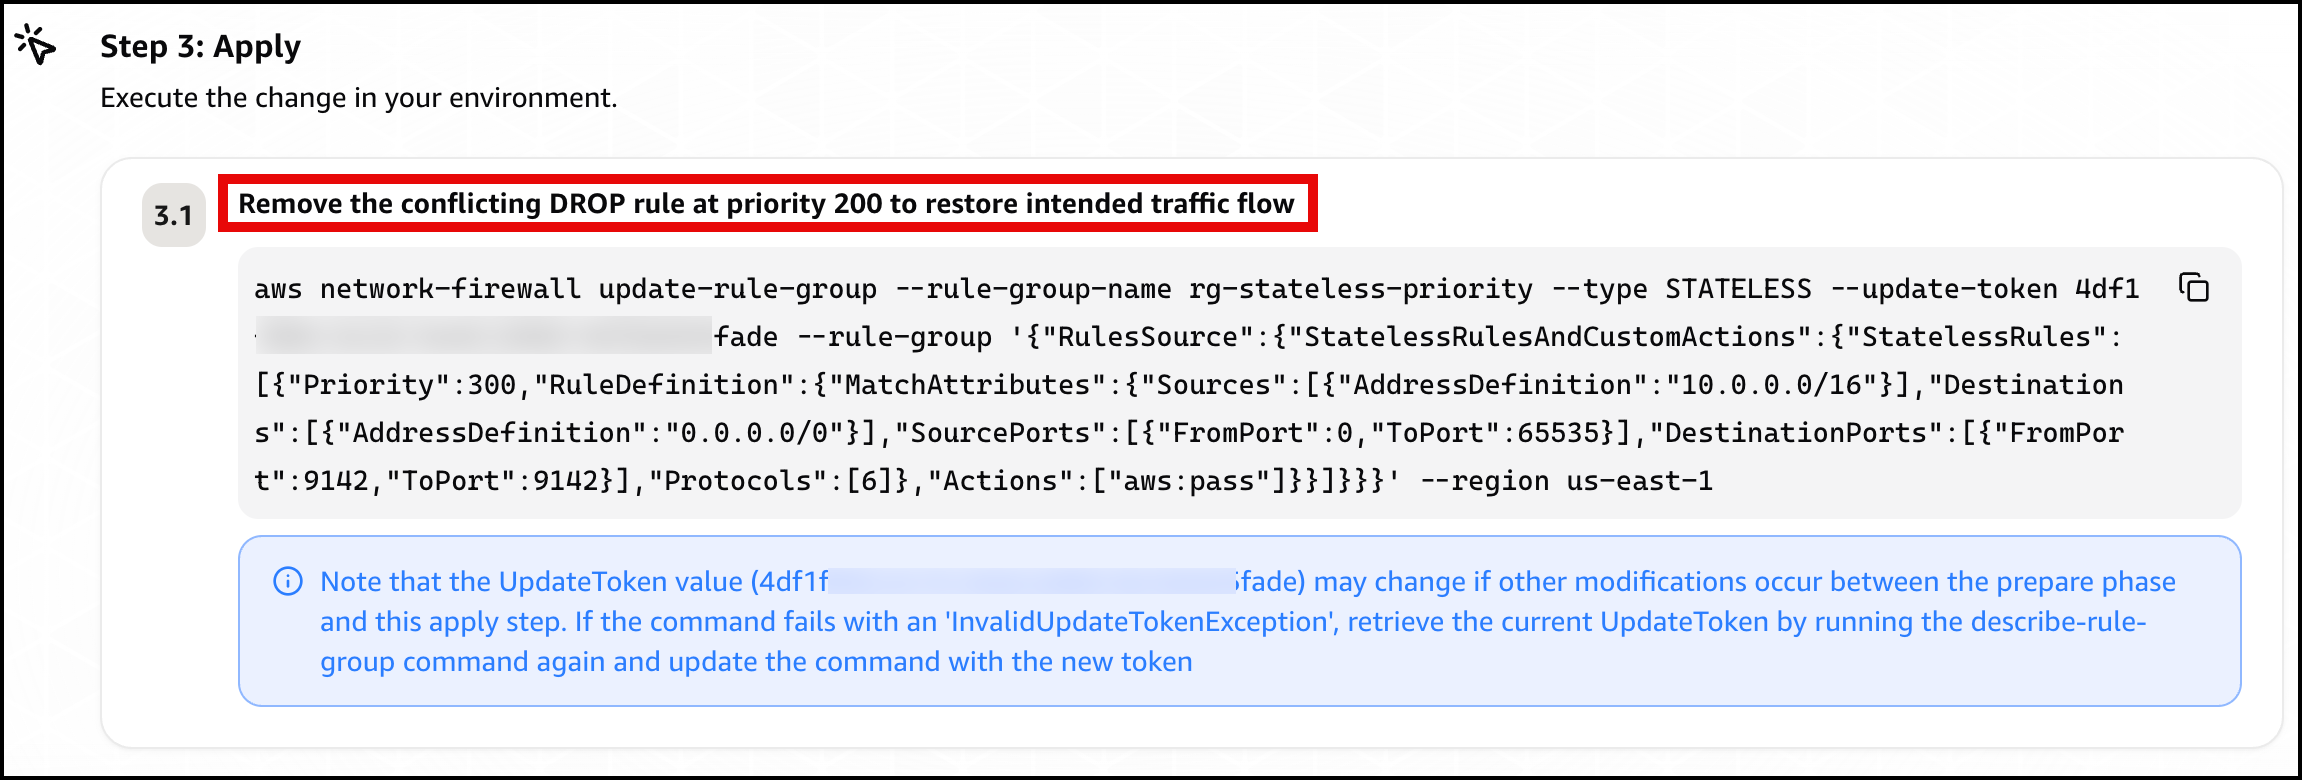
Figure 11: Scenario 2 – The mitigation plan

Figure 11: Scenario 2 – The mitigation plan

Confirm recovery. Apply the change the agent recommends. After the allow rule is ahead of the drop rule again, Alarm-2 clears and the card returns to green. Move on to Scenario 3.

Scenario 3. Asymmetric cross Availability Zone routing drop

At baseline, the protected subnet in each Availability Zone routes its egress through the firewall endpoint in that same Availability Zone , and the matching return route uses that same endpoint. One endpoint sees both directions of the flow, so the stateful engine completes the handshake. The workload runs in the protected subnet in us-east-1a (CIDR 10.0.4.0/24), so at baseline its egress and its return both use the us-east-1a firewall endpoint.

Introduce the change. Make the flow asymmetric by sending egress out one Availability Zone endpoint while the return comes back through the other. This takes two route edits, and both are required. With only the first edit the flow can still complete, so the alarm will not trigger until both are saved. It makes no firewall-policy change, mirroring a real multi-Availability-Zone routing mistake.

To create asymmetric cross Availability Zone routing

  1. Go to the Amazon VPC console and choose Route tables in the navigation pane.
  2. Flip the egress. Select the NfNetworkStack/SampleVpc/protectedSubnet1 route table (the us-east-1a protected subnet, where the workload runs). On the Routes tab, choose Edit routes. Its 0.0.0.0/0 route currently targets the us-east-1a firewall endpoint. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1b firewall endpoint, then choose Save changes.
  3. Move the return. Select the NfNetworkStack/SampleVpc/publicSubnet2 route table (the us-east-1b public subnet, where egress now exits). Choose Edit routes, then Add route. For the destination enter the workload CIDR 10.0.4.0/24. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1a firewall endpoint. Choose Save changes.

After both edits, a flow’s egress leaves through the us-east-1b endpoint while its return is directed to the us-east-1a endpoint. Neither endpoint sees the whole flow.
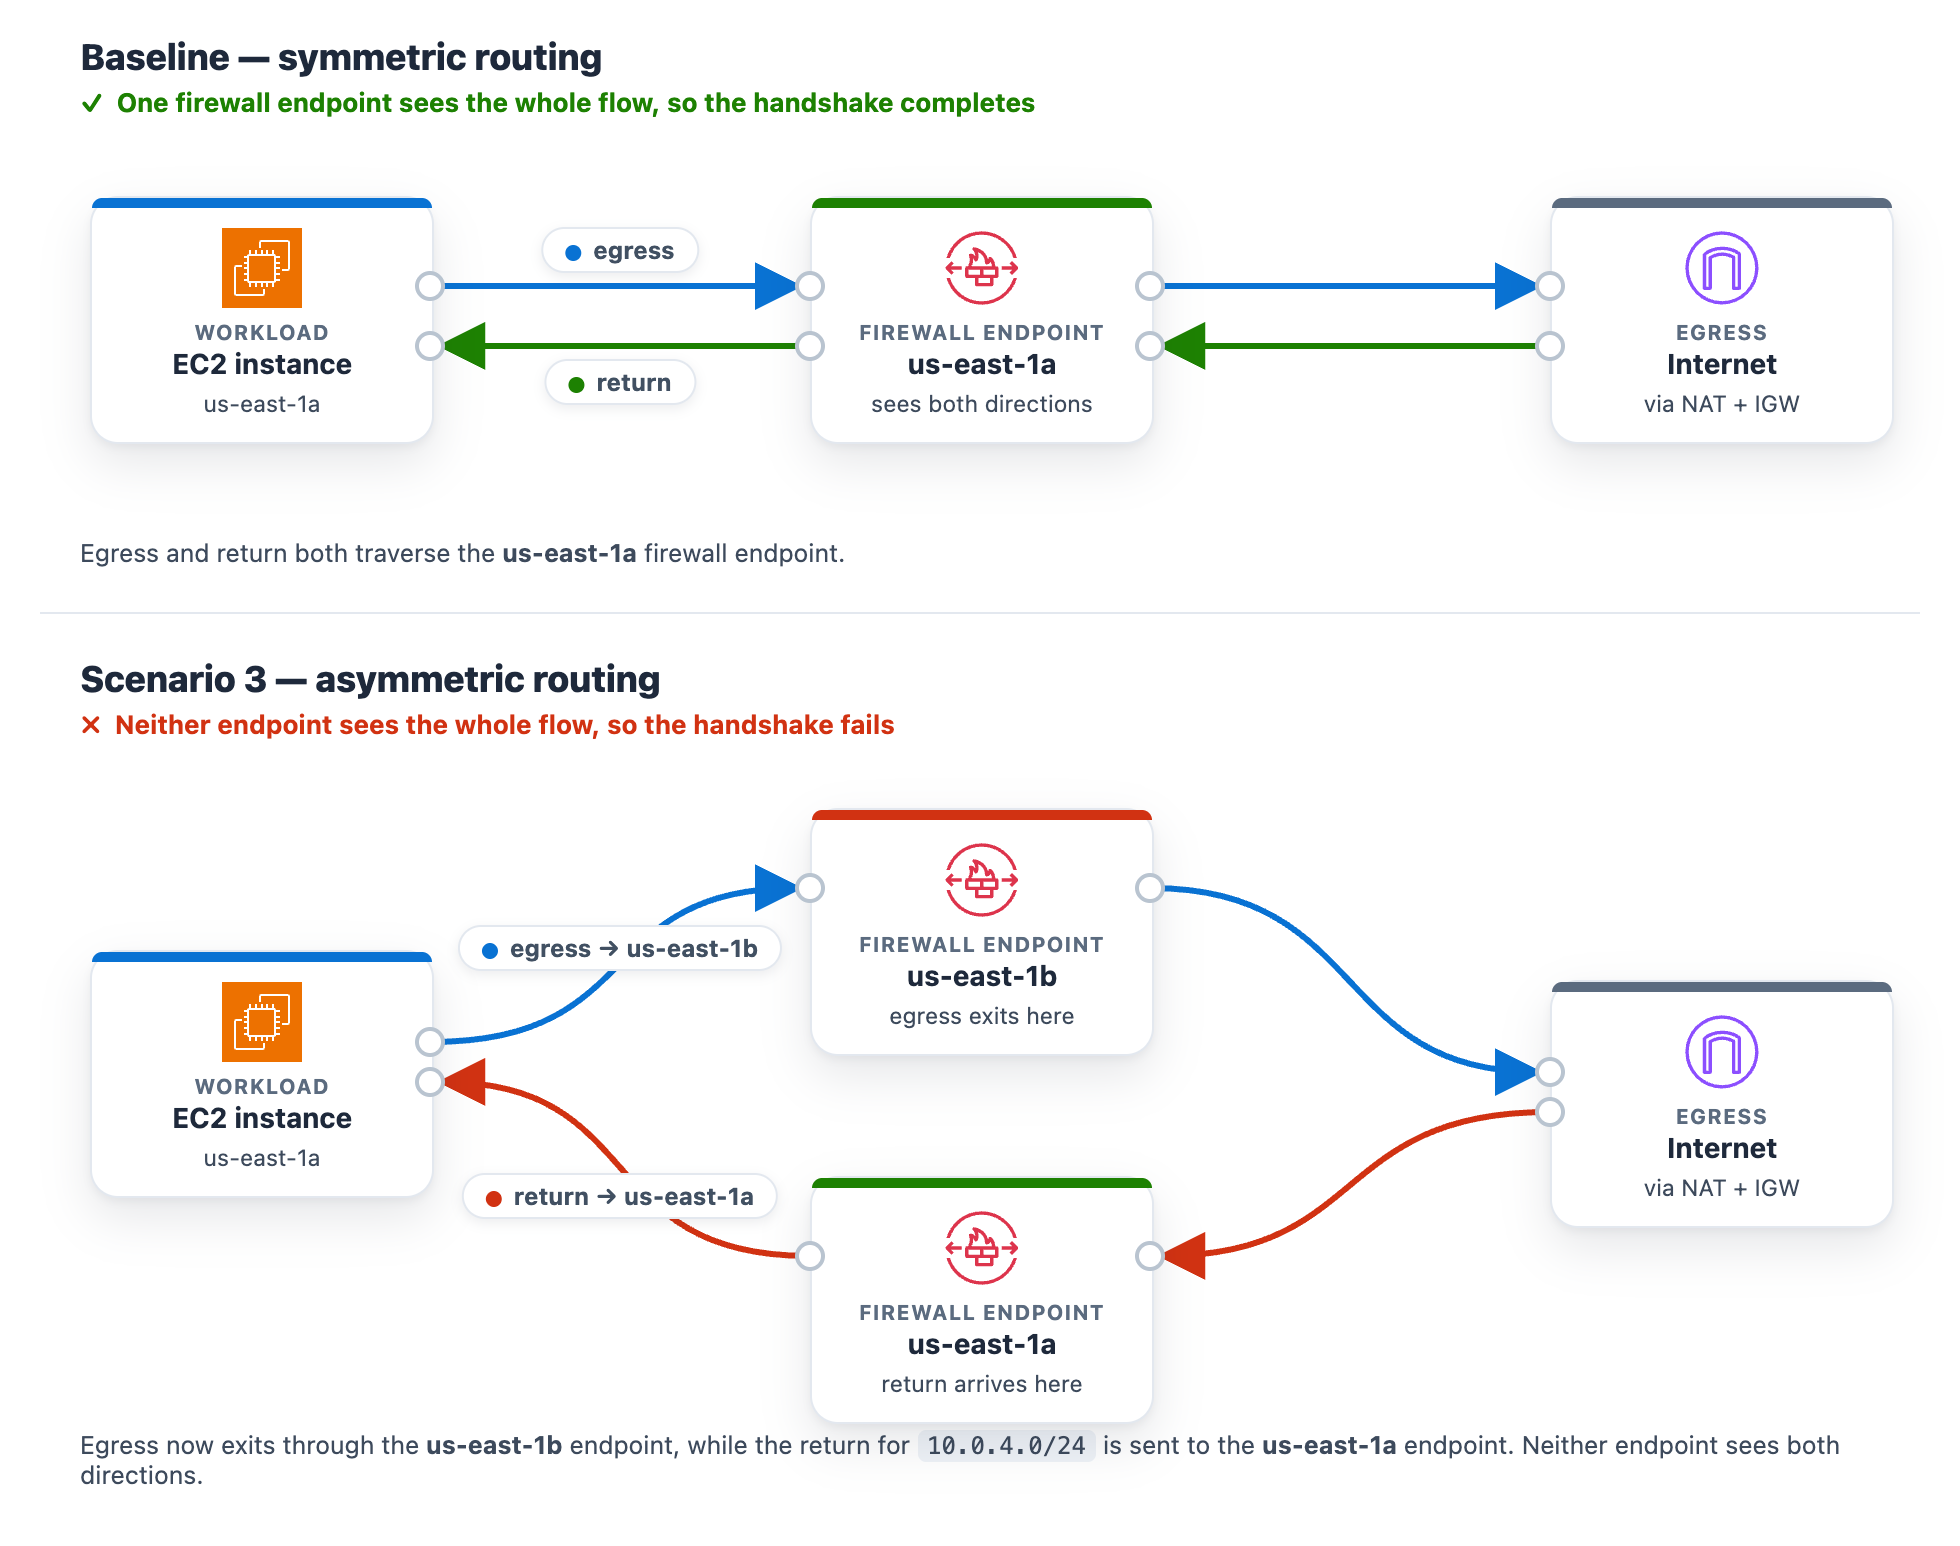
Figure 12: Scenario 3 routing change breaking the flow’s symmetry

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

What happens. A new connection leaves through one endpoint. Its return arrives at the other endpoint, which never saw the connection open, so the handshake fails. Unlike Scenarios 1 and 2, this affects the whole subnet, so all egress stops and Alarm-2 and Alarm-3 both move to ALARM. The AWS/NetworkFirewall DroppedPackets alarm (Alarm-1) stays quiet because no endpoint is making a drop decision. The flow is lost to asymmetric routing rather than counted as a firewall drop. This is why monitoring application connectivity matters. A routing fault is invisible to the firewall’s own drop counter. On the status page, the Scenario 2 card reads DROPPED (with the condition “Stateless rules dropping the monitored traffic class”) and the Scenario 3 card reads DROPPED (with the condition Return traffic dropped by asymmetric cross-Availability-Zone routing), while the Scenario 1 card stays Healthy (Figure 13). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, while the egress path from the firewall through the NAT gateway and the TLS :9142 and HTTPS · routing lines to the test endpoint turn red, which the legend defines as dropped (root cause).
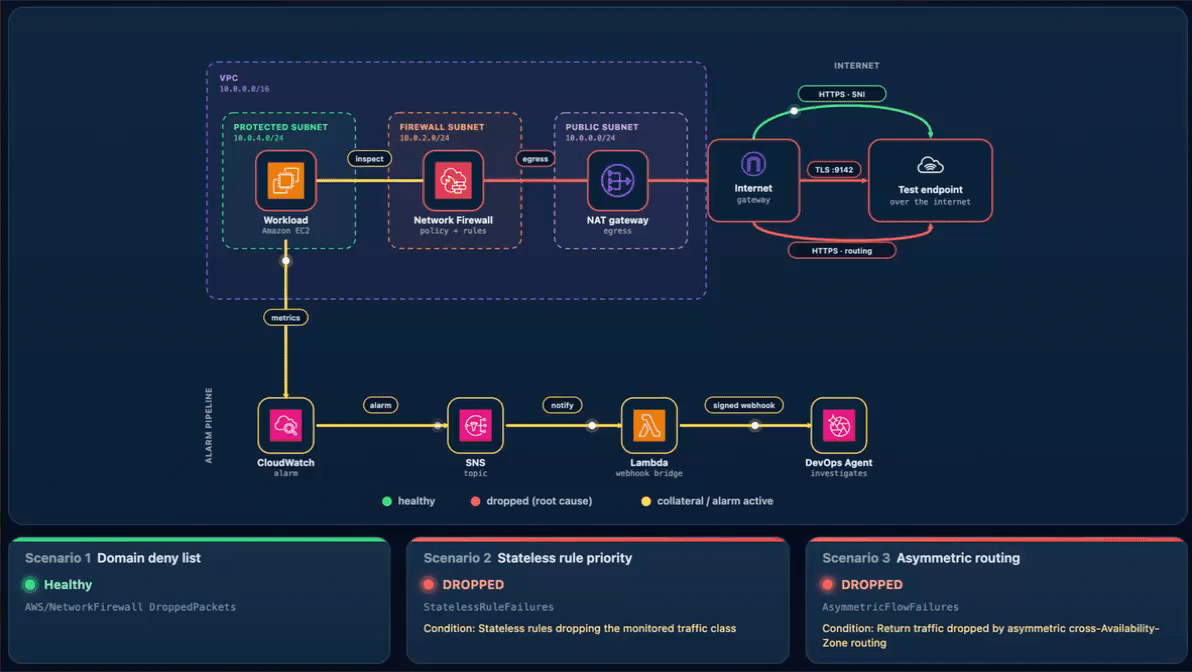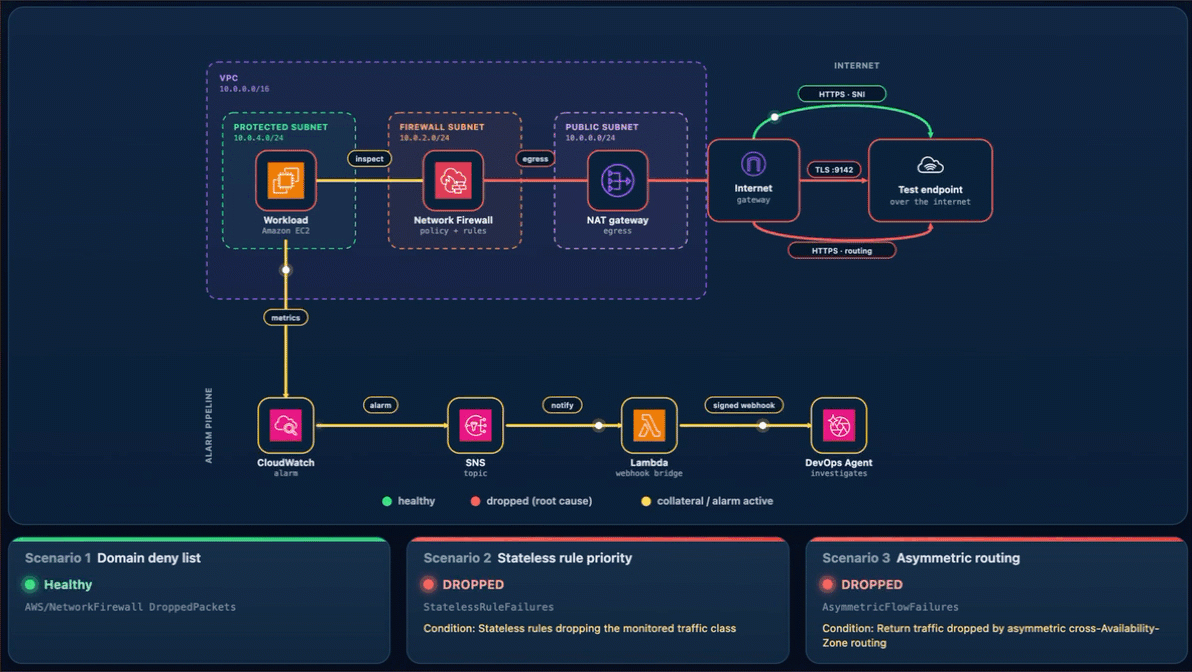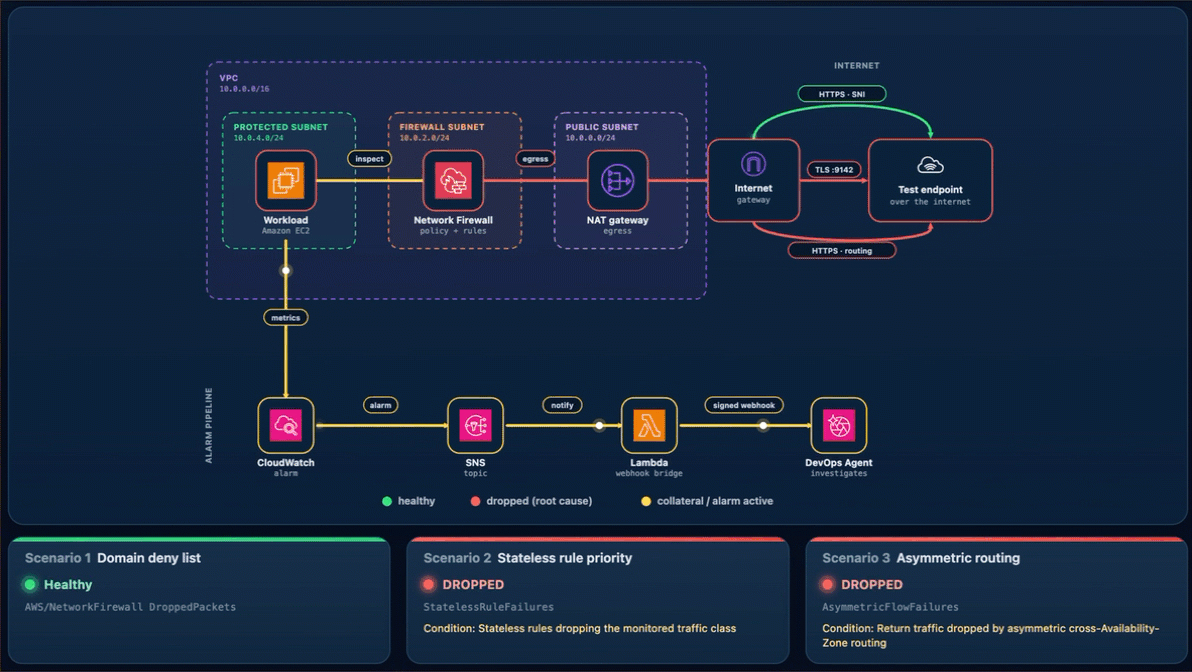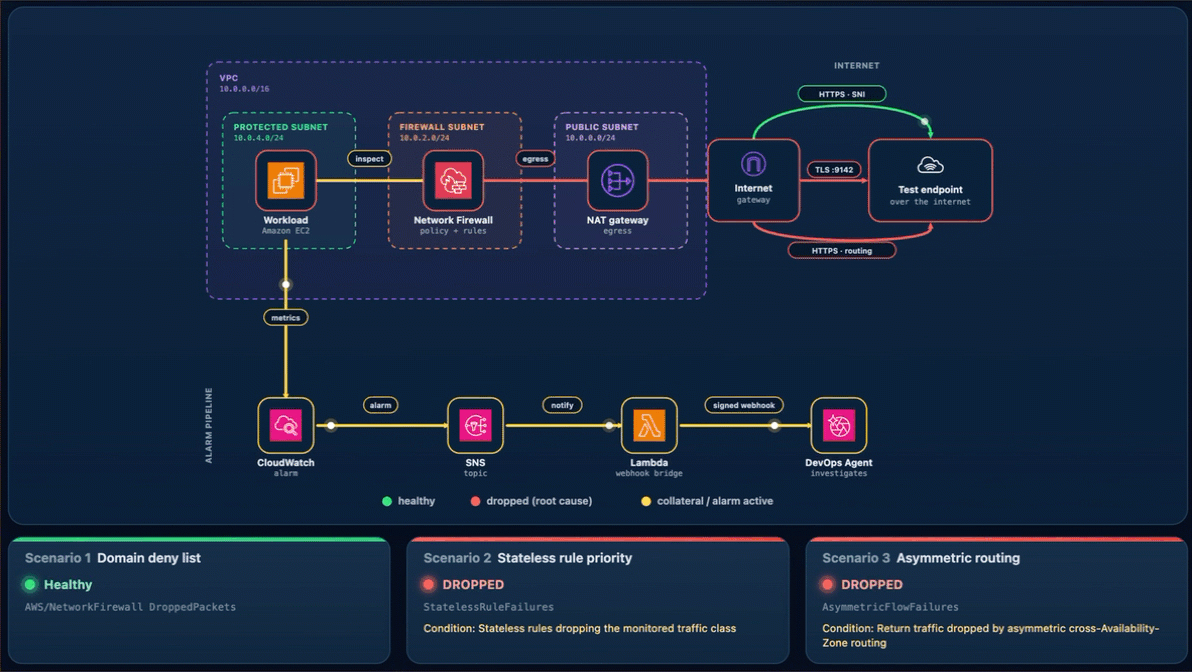
Figure 13: Scenario 3 – The status page during a path-wide outage

Figure 13: Scenario 3 – The status page during a path-wide outage

Let DevOps Agent investigate. Both Alarm-2 and Alarm-3 fire in the same datapoint. DevOps Agent recognizes them as linked and merges them into a single investigation:

  1. Reads the flow logs and sees bidirectional TLS connections stop abruptly, with only one-way traffic remaining and no flows reaching the established state.
  2. Reads the firewall metrics and sees received and passed packets shift from one Availability Zone to the other at the moment of the change.
  3. Calls DescribeRouteTables and finds the egress route pointing at one Availability Zone firewall endpoint while the return route points at the other.
  4. Searches CloudTrail and surfaces the ReplaceRoute and CreateRoute calls by the same user, about a minute before both alarms fired.
  5. Reports the root cause as that asymmetric routing change. Recommends restoring symmetric same-Availability-Zone routing so egress and return traverse the same endpoint.
  6. Presents this as a plan you review and apply, not an automatic change.

A mitigation plan is a recommendation you review, not an automatic change, and the right fix depends on the intended design. Restoring symmetric routing can mean sending the workload subnet’s egress back through its own-Availability-Zone firewall endpoint (this sample’s architecture) or, in a design that doesn’t inspect this path, back through a NAT gateway. The agent infers a plausible target from what it can observe, so review the specific route it proposes against your intended topology before you apply it. (Connecting your pipeline or infrastructure-as-code, covered in the next section, lets the agent recommend the target that matches your design.)

In the DevOps Agent Operator Web App view, the agent restates the Alarm-3 (AsymmetricFlowFailures) trigger and confirms the workload’s egress to a monitored endpoint is being blocked by the Network Firewall (Figure 14).
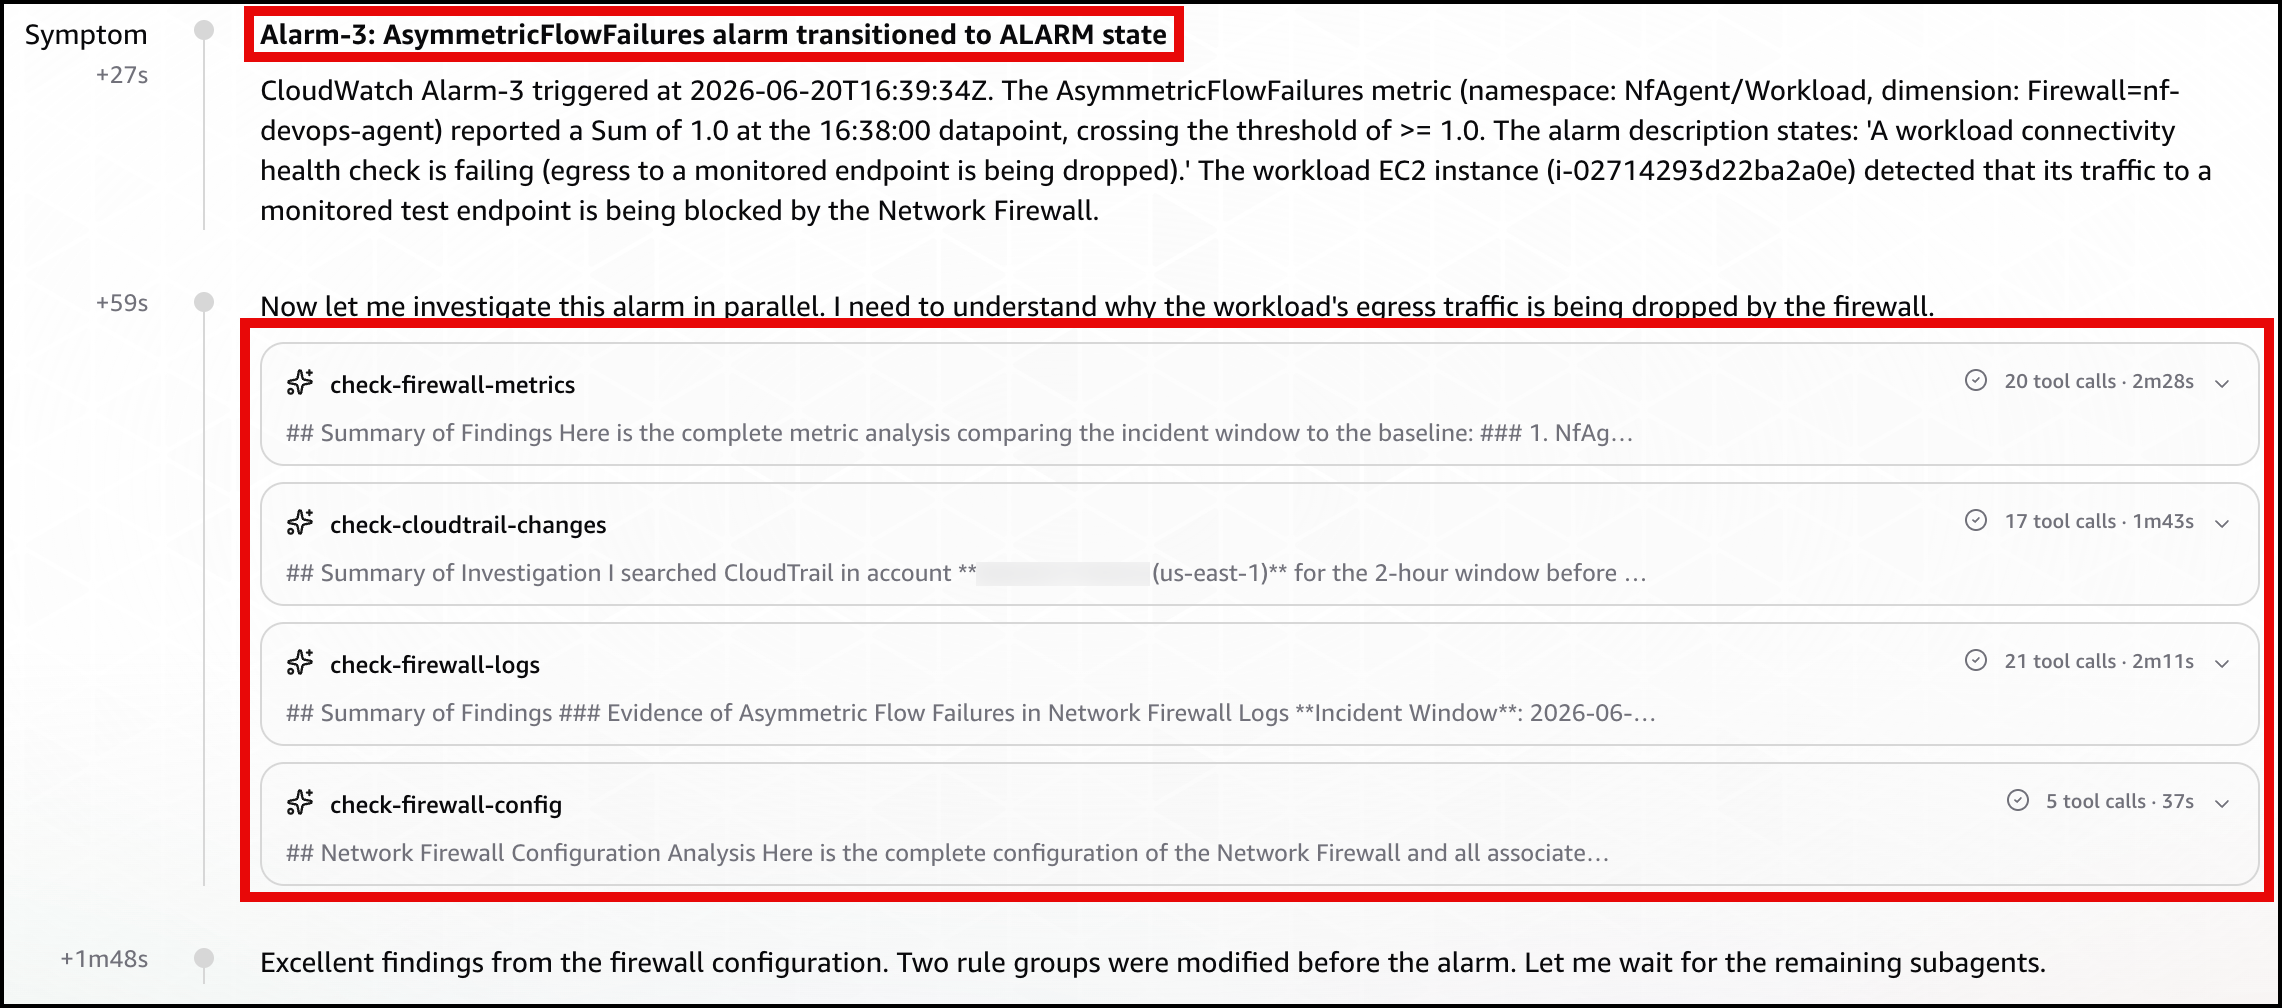
Figure 14: Scenario 3 – The symptom

Figure 14: Scenario 3 – The symptom

Next, the agent identifies the root cause: manual route table changes that created cross-AZ asymmetric routing through the network firewall, breaking its symmetric routing requirement (Figure 15)
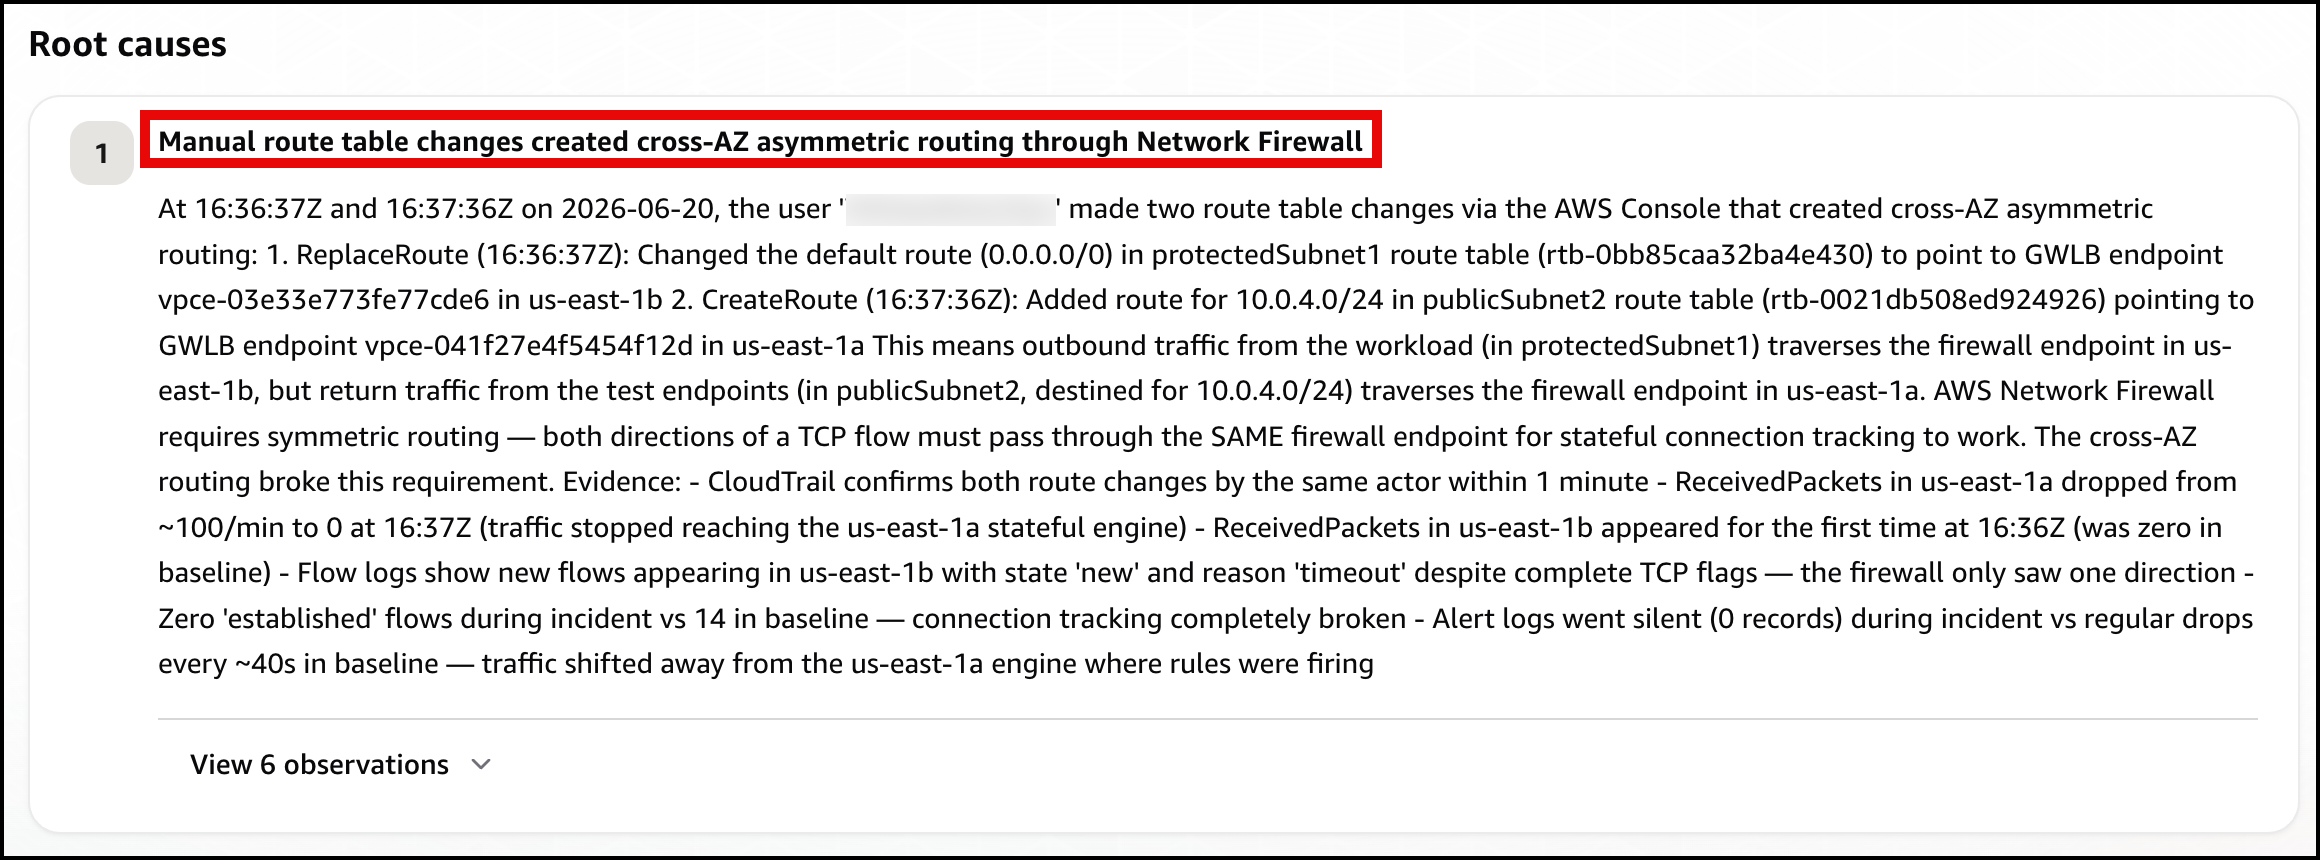
Figure 15: Scenario 3 – The root cause

Figure 15: Scenario 3 – The root cause

Finally, the agent presents a mitigation plan, recommending you restore symmetric routing by pointing protectedSubnet1‘s default route back to the same Availability Zone firewall endpoint, so one endpoint sees both directions of the flow again (Figure 16).
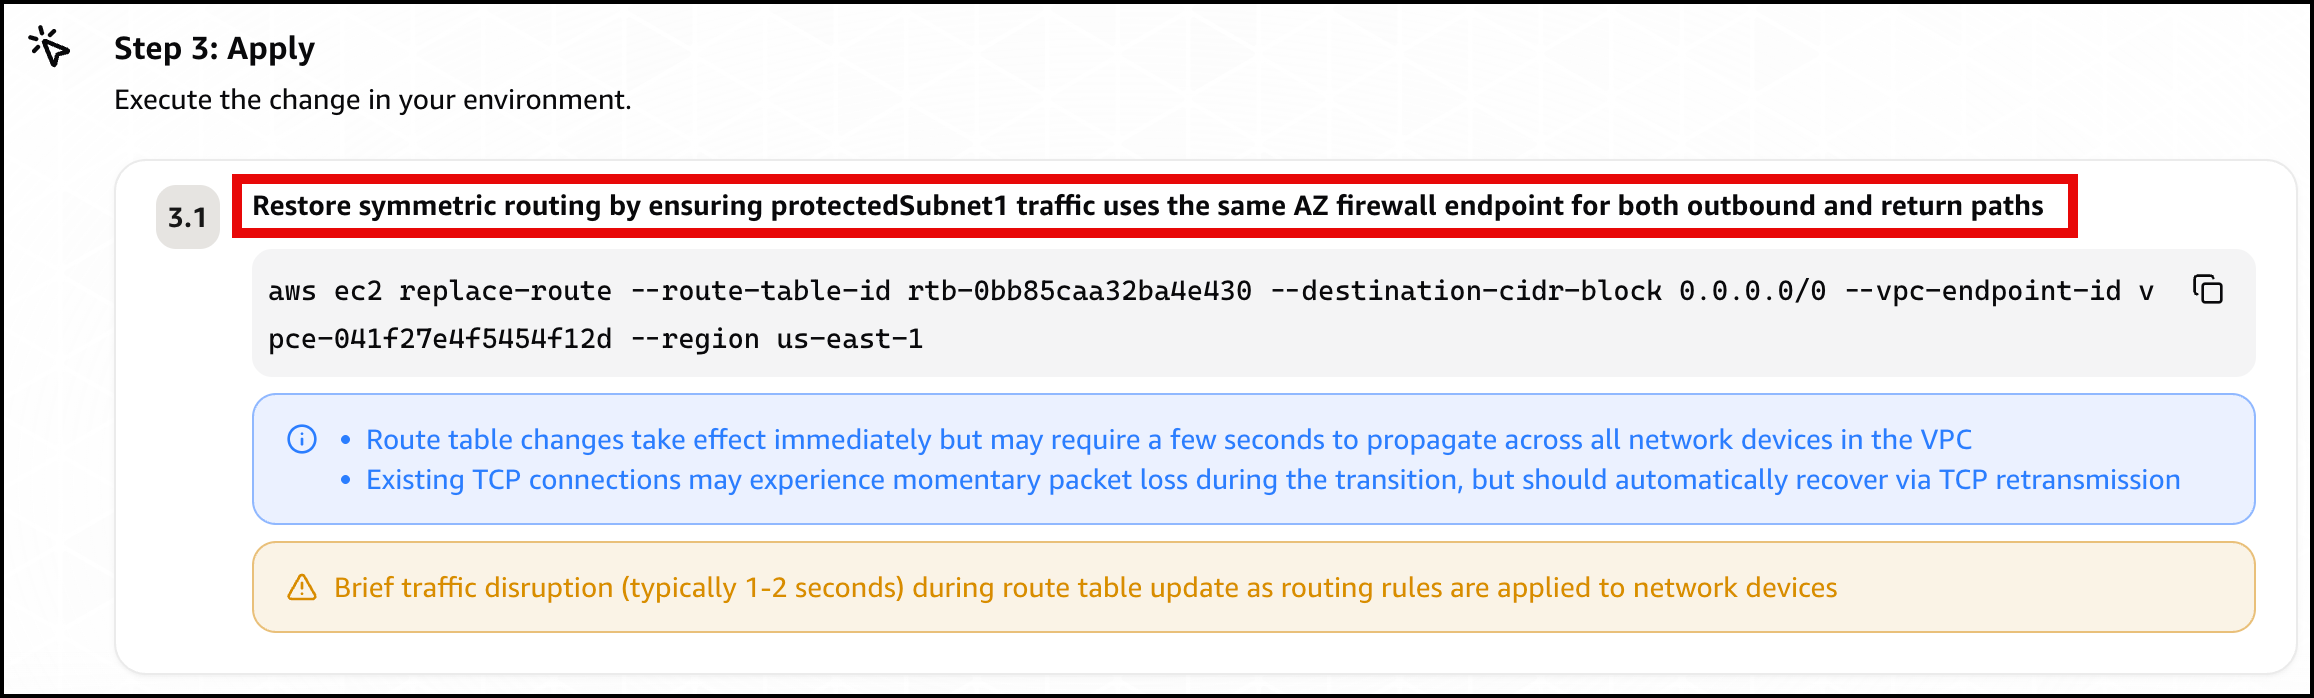
Figure 16: Scenario 3 – The mitigation plan

Figure 16: Scenario 3 – The mitigation plan

Confirm recovery. Apply the change the agent recommends, after checking the route target matches your intended design. After the workload subnet’s egress and return use the same Availability Zone firewall endpoint again, the control probe recovers, the alarms clear, and every card returns to green.

Further considerations

In production a single change can trigger several alarms at the same time, as Scenario 3 shows. DevOps Agent links related investigations and works them as one, so you review a single root cause. You can validate the linked findings or unlink an alarm to investigate it independently. If you would rather collapse alarms before they reach the agent, you can add correlation logic in the bridge Lambda function, buffering and grouping by firewall. You can also add email, Amazon Simple Queue Service (Amazon SQS), or HTTP subscribers to the SNS topic, or add the webhook Lambda function to a topic you already run. DevOps Agent produces a mitigation plan but does not change your environment on its own.

You can also give the agent more to work with. DevOps Agent connects to source repositories and CI/CD pipelines, integrating with GitHub (including GitHub Enterprise Server and GitLab Self-Managed through a private connection). It can associate AWS resources with deployments of AWS CloudFormation, AWS CDK, Amazon Elastic Container Registry (Amazon ECR) images, and Terraform. With deployed configuration and recent deployment events in view, the agent correlates the disruption against the change that introduced it and recommends a fix matching your intended design. For this sample, that means recommending the workload subnet’s own Availability Zone firewall endpoint rather than a generic symmetric path.

DevOps Agent also supports proactive incident prevention. It analyzes patterns across past investigations and delivers recommendations to prevent similar issues from recurring, including governance recommendations that strengthen deployment processes and pipeline controls. For Network Firewall rule changes, this means the agent can recommend guardrails for your CI/CD pipeline based on the classes of misconfigurations it has already resolved. You can access these recommendations through the Improvements page in the DevOps Agent Operator Web App.

Clean up

Clean up the environment with one command.

bash scripts/destroy.sh

It reverts any active scenario, runs cdk destroy for all stacks, and sweeps for stragglers by the Project = nf-devops-agent tag. The main cost drivers are the two Network Firewall endpoints, the NAT gateways (one in the main VPC for each Availability Zone, one in the test-endpoint VPC), and the test endpoint’s load balancers. Each of these bills at an hourly rate for as long as it’s provisioned, whether or not traffic is flowing, so a stack left running continues to accrue charges around the clock even while idle. Running the scenarios and tearing the stack down the same day limits the cost to a few active hours rather than days of idle hourly charges.

Conclusion

In this post, we showed you how AWS DevOps Agent accelerates troubleshooting for three common network firewall connectivity issues. The first was a domain deny list. The second was a stateless priority inversion. The third was an asymmetric cross-AZ routing drop. For each one, DevOps Agent investigated the drop and returned a root cause with a mitigation plan you approve before applying. The first scenario triggered on a prebuilt Network Firewall metric, and the other two on application health metrics. That shows both ways to alarm on a firewall problem through one pipeline.

The pattern isn’t specific to Network Firewall. The same flow fits any service that emits CloudWatch metrics and logs, such as AWS WAF, security groups, and network ACLs. Clone the sample repository to explore the solution, then apply what you learn to your own firewall, application, and alarms. For more details, see the AWS Network Firewall Developer Guide and the AWS Network Firewall pricing page. Start with the Getting Started with AWS DevOps Agent guide to connect your first webhook.
Salman Ahmed

Salman is a Senior Technical Account Manager at AWS, specializing in helping customers design, implement, and optimize their AWS environments. He combines deep networking expertise with a passion for exploring emerging technologies to help organizations get the most out of their cloud investments. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Threat tactic spotlight: Subdomain takeover

Post Syndicated from Matt Gurr original https://aws.amazon.com/blogs/security/threat-tactic-spotlight-subdomain-takeover/

In this blog post you’ll learn how to detect and prevent subdomain takeover – a tactic where threat actors exploit dangling DNS records to redirect traffic to attacker-controlled resources. We’ll explain the issue, how the situation arises, and how you can use various AWS features and services to help mitigate the impact of this tactic.

Under the shared responsibility model, securing configurations in the cloud is your responsibility. AWS supports you through strong defaults, guidance in the Security Pillar of the Well-Architected Framework, and security services to help you meet that responsibility. The AWS Customer Incident Response Team (AWS CIRT) also monitors for new and trending tactics that threat actors use to exploit specific customer configurations, so that you can make informed design decisions and improve your response plans.

AWS CIRT has observed threat actors actively scanning for public DNS CNAME records that point to resources that no longer exist, looking for subdomain takeover opportunities.

Note: The subdomain takeover tactic does not leverage vulnerabilities of AWS services. It exploits a dangling DNS record to redirect traffic to an attacker-controlled resource.

Quick DNS Primer

CNAME Records: A CNAME (Canonical Name) record is a DNS entry that points one domain name to another. For example, api.example.com can be configured to point to api.example.s3-website-us-east-1.amazonaws.com. This feature of DNS enables users to configure a memorable, human-friendly domain name while the actual resource lives at a longer, machine-generated AWS hostname. A security issue emerges when the target resource is deleted but the CNAME record pointing to it remains – creating a “dangling” record.

Dangling Records: When a resource (like an S3 bucket) is deleted but the DNS record pointing to it is left behind, that DNS record becomes “dangling”, pointing to a resource that no longer exists. For resources in globally shared namespaces, threat actors can potentially reclaim the name of your deleted resource and serve malicious content through your DNS record.

What is subdomain takeover?

A subdomain is a prefix added to a domain that allows you to organize access to your resources. A subdomain takeover occurs when you delete the underlying resource and a threat actor creates a new resource with the same name to take advantage of the DNS records still pointing to it.

A subdomain takeover is possible when a CNAME record points to an AWS resource that uses a globally shared DNS namespace where the resource name can be chosen by any AWS customer. The following AWS resources meet these criteria:

Amazon S3 (global namespace): Bucket names like mybucket.s3.amazonaws.com are globally unique and can be claimed by any account if the bucket is deleted. Note: S3 buckets created with account regional namespaces (launched March 2026) are scoped to your account and are not subject to this issue.

Amazon CloudFront: Distribution domain names like d111111abcdef8.cloudfront.net are assigned by AWS and cannot be chosen by an attacker. However, if you delete a distribution and another customer creates one that happens to receive the same domain name, a dangling CNAME could resolve to their content.

AWS Elastic Beanstalk: Environment names like myapp.elasticbeanstalk.com are globally unique and can be claimed by any account if the environment is terminated.

Resources like Amazon VPC, Amazon EC2 instances, or private hosted zones are not subject to this tactic because they do not expose globally claimable DNS namespaces.

MITRE ATT&CK classifies this technique under T1584.001: Compromise Infrastructure – Domains.

Analyzing an example scenario

Consider the following scenario:

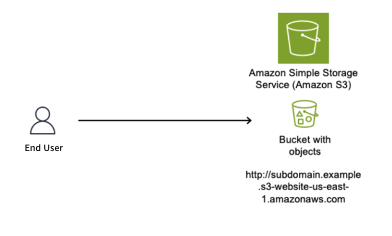
You create a DNS CNAME record pointing to your S3 website endpoint. The subdomain subdomain.example.com now resolves to subdomain.example.s3-website-us-east-1.amazonaws.com, which serves content from the S3 bucket named subdomain.example. If your team deletes the bucket and forgets to delete the DNS record, users that navigate to the site will see an error stating that the bucket doesn’t exist. However, at this point, if a threat actor sees this error and moves in to claim the bucket name, they will be able to set up their own site that users will see when they navigate to the subdomain.example.com site.

Figure 1 shows an S3 bucket named subdomain.example (a globally unique bucket name) configured to host a static website, with the S3 website endpoint subdomain.example.s3-website-us-east-1.amazonaws.com.

Figure 1: S3 bucket configured as a static website

Figure 1: S3 bucket configured as a static website

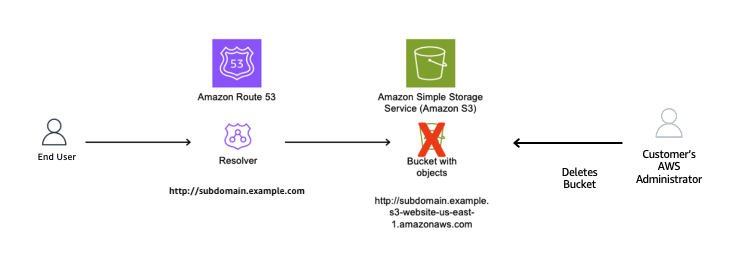
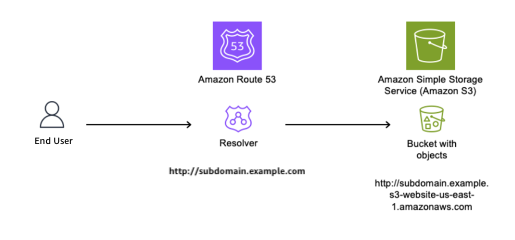
As shown in Figure 2, we use Amazon Route 53 to create a CNAME record to resolve to our Amazon domain name; to give users a friendly name and so they do not have to remember the long S3 website name in URLs.

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

The customer’s AWS administrator decides to stop serving content from the S3 bucket and deletes it, as shown in Figure 3.

Figure 3: Resource deleted without removing the CNAME record

Figure 3: Resource deleted without removing the CNAME record

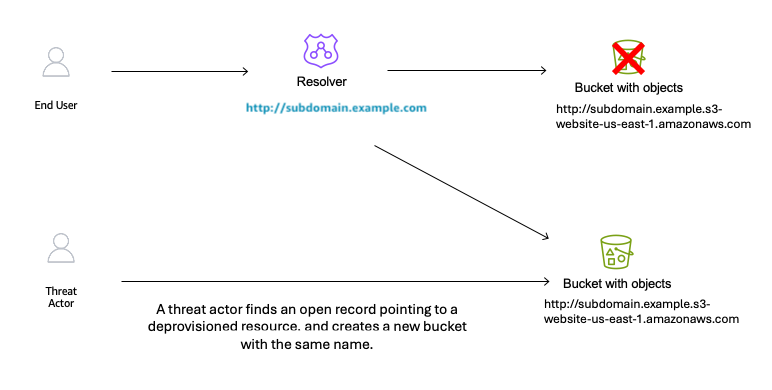
With the S3 bucket deleted and the CNAME record still in place, the DNS record is now dangling. A threat actor identifies this situation and creates a new S3 bucket with the same global name subdomain.example in an AWS account that the threat actor controls, as shown in Figure 4. The threat actor can now serve content from this new bucket, including potentially malicious content. End users remain unaware of this switch and continue to access subdomain.example.com, trusting the content because it appears to originate from a URL they recognize.

Figure 4: Subdomain takeover happens

Figure 4: Subdomain takeover happens

Potential impacts of a sub-domain takeover

Consider these potential impacts:

Reputation risk: There is a potential risk to your organization’s reputation, because you don’t control the content being served from the threat actor’s site that your DNS record points to.

Potential exposure to phishing campaigns: Users within your organization might have the subdomain bookmarked in their browser, not knowing the resource is no longer available, then unsuspectingly navigate to the site that now hosts malware or is used to phish user credentials.

Blocking: If the subdomain is flagged by security vendors for malicious activity, it could impact your business operations.

Financial loss: Subdomain takeover incidents can result in a financial impact due to the potential disruption to service delivery as you deal with the event.

Proactive detection

AWS Config for proactive detection

For proactive detection, you can use AWS Config to continuously monitor your Route 53 CNAME records and verify that the target resources exist in your account.

Prerequisite: This approach requires AWS Config recorder to be enabled for the resource types you want to monitor (S3 buckets, CloudFront distributions, Elastic Beanstalk environments). If Config isn’t recording a resource type, it won’t appear in the inventory check. For more information, see Setting up AWS Config with the console.

Why use AWS Config inventory instead of DNS resolution checks?

A common approach is to check whether a CNAME resolves to a valid endpoint. However, this method has a critical flaw: if an attacker has already claimed the resource, DNS resolution will succeed – to their resource, not yours. You would have no indication that you don’t own what’s responding.

By querying AWS Config’s recorded configuration items, you’re checking whether the resource exists in your account inventory, not just whether something responds at that DNS name. This approach correctly identifies dangling CNAMEs even after a takeover has occurred.

Implementation approach:

Account-level vs. organization-level scope

The reference implementation queries AWS Config inventory within a single account. This means that if a CNAME record in Account A points to a resource that legitimately exists in Account B within the same AWS organization, the rule will flag it as NON_COMPLIANT.

For organizations that share resources across accounts, you can modify the solution to use an AWS Config Aggregator, which queries resource inventory across all accounts in your organization. This is similar to how IAM Access Analyzer supports both account-level and organization-level scopes. To use this approach, you need an organization-level Config Aggregator already configured, and the Lambda function’s IAM role needs the config:SelectAggregateResourceConfig permission.

We recommend starting with account-level scope for simplicity, then expanding to organization-level if your environment includes cross-account resource sharing.

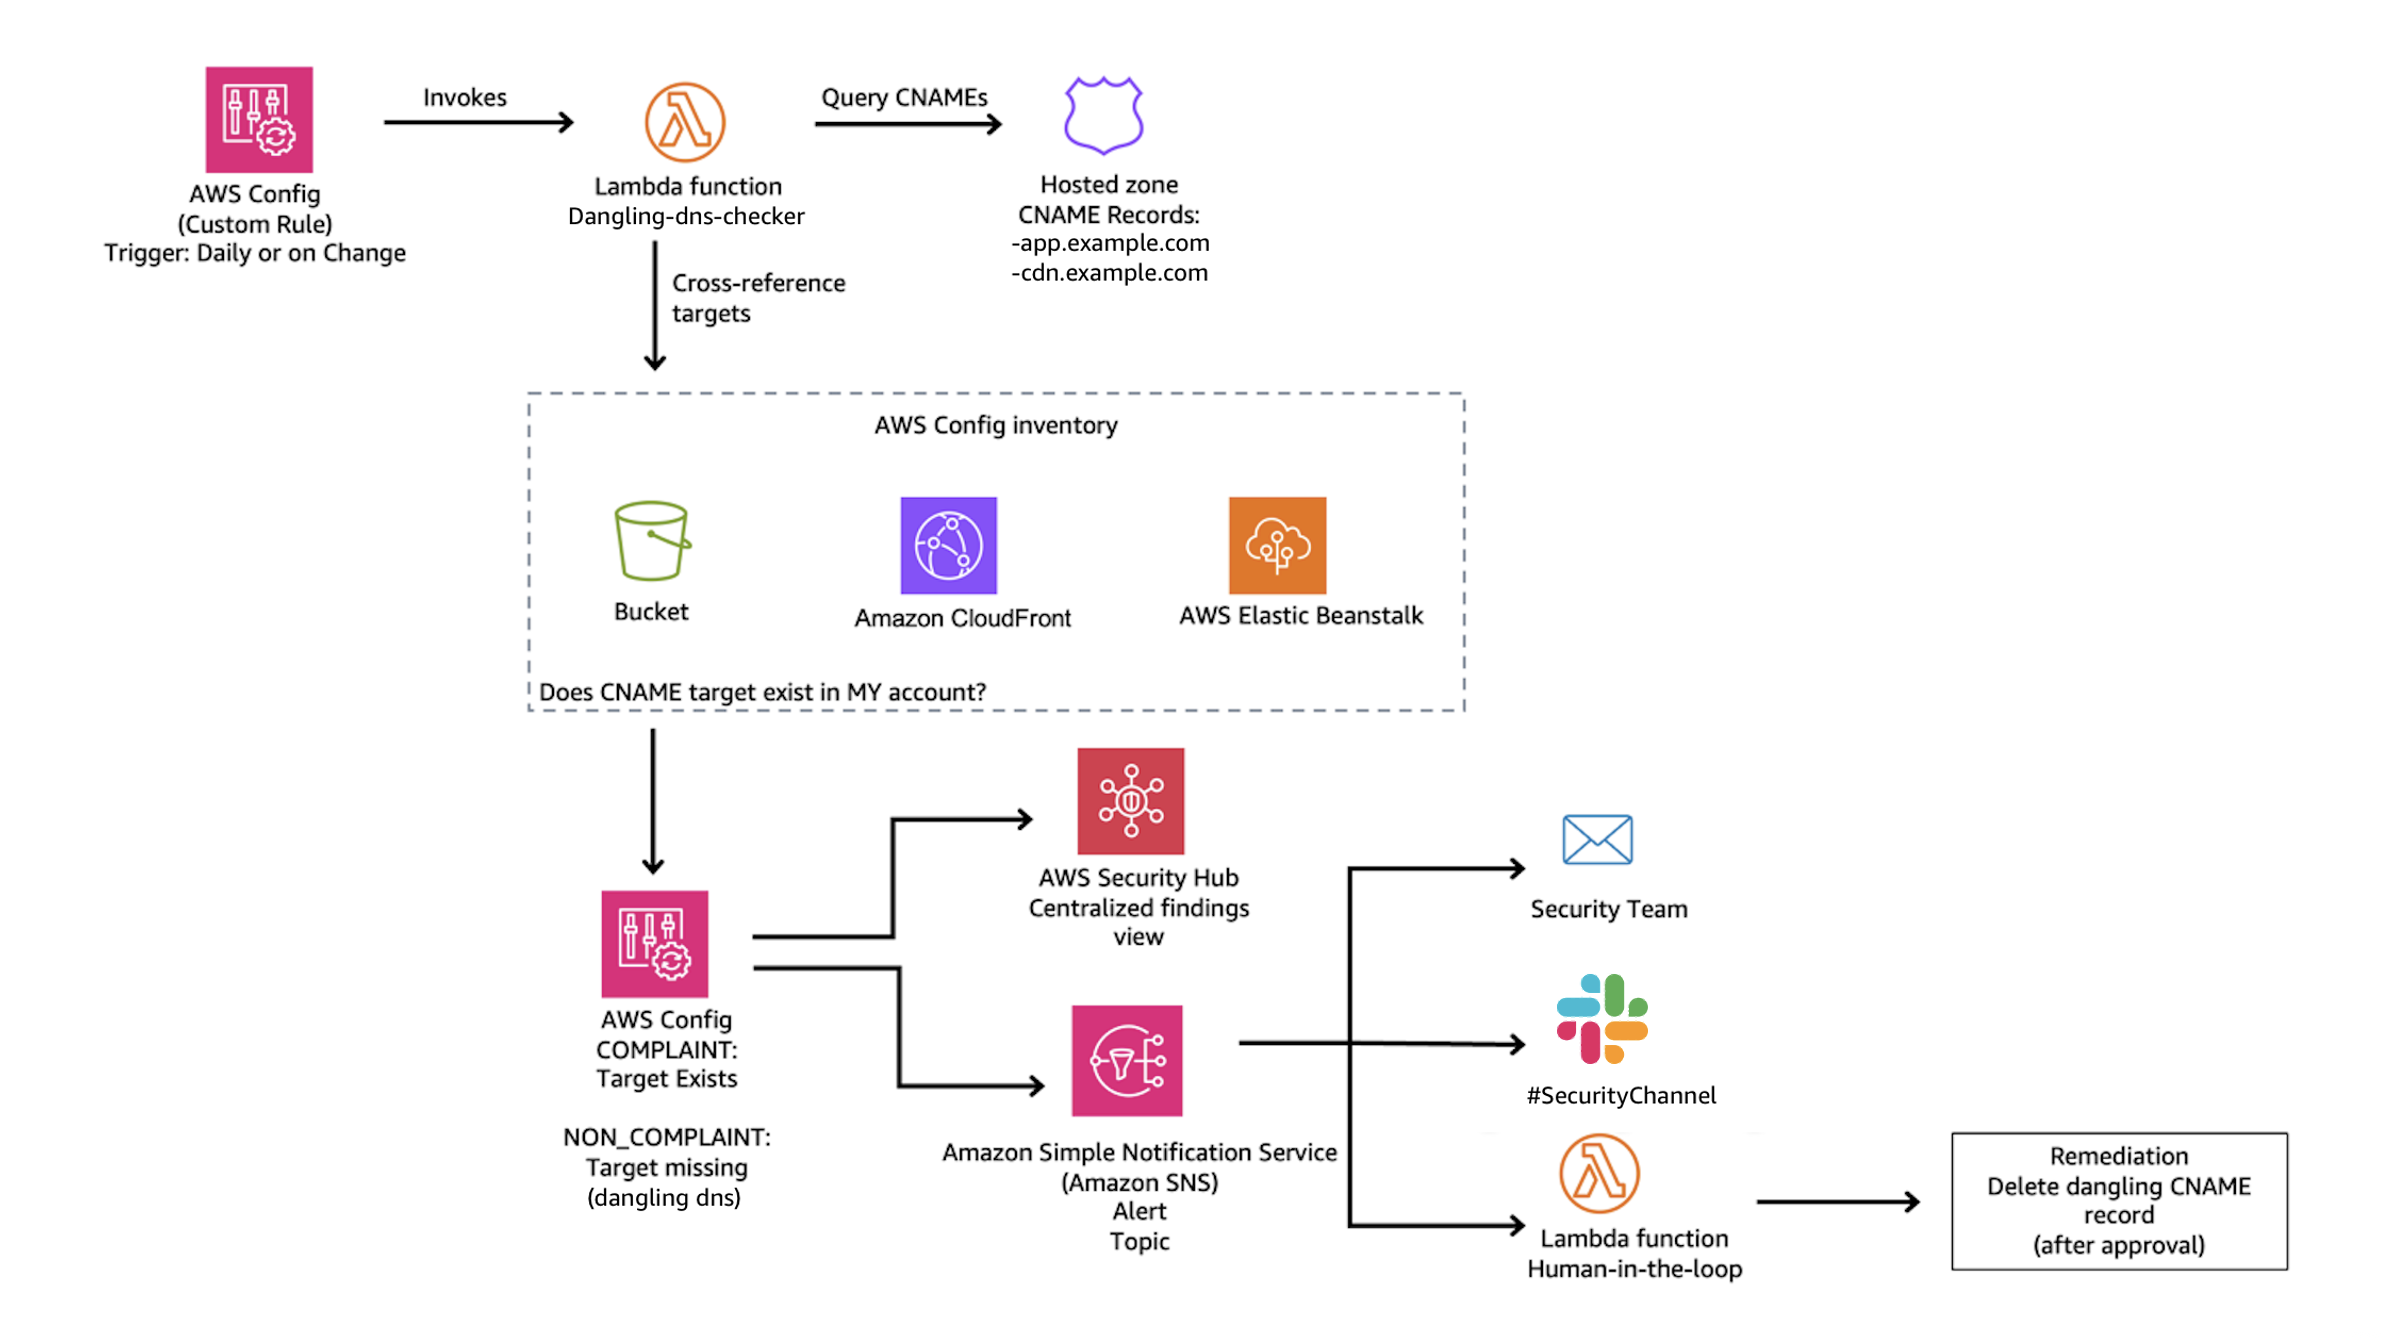
The main idea is to create a custom AWS Config rule that queries your Route 53 hosted zones for CNAME records, then parses each CNAME target to determine whether it points to a known AWS resource pattern such as S3, CloudFront, or Elastic Beanstalk. For each match, the rule cross-references the target against your AWS Config inventory to verify that the resource actually exists in your account. If the resource isn’t found, the rule marks the CNAME record as NON_COMPLIANT, surfacing it for review.

The Config rule should focus on known AWS resource patterns:

  • S3: *.s3.amazonaws.com, *.s3-website-<region>.amazonaws.com
  • CloudFront: *.cloudfront.net
  • Elastic Beanstalk: *.elasticbeanstalk.com

Note: CNAME records pointing to external third-party services are outside the scope of this detection mechanism, as those resources won’t appear in your AWS Config inventory.

NON_COMPLIANT findings from your Config rule can be routed to AWS Security Hub for centralized visibility, or trigger SNS notifications to alert your security team.

Figure 5: Dangling DNS Detection Solution

Figure 5: Dangling DNS Detection Solution

Reference implementation:

We’ve published a complete implementation of this detection approach as an open-source solution. The solution deploys a Lambda function that discovers CNAME records across all your Route 53 hosted zones and uses pattern matching to identify targets pointing to S3, CloudFront, and Elastic Beanstalk. It then queries your AWS Config inventory to verify whether each target resource still exists in your account. When a dangling record is detected, the solution generates a HIGH severity finding in Security Hub and can optionally send SNS notifications to alert your security team. A CloudWatch metrics dashboard is also included for ongoing compliance tracking.

Deployment:

# Clone the repository
git clone https://github.com/aws-samples/sample-dangling-dns-detection
cd sample-dangling-dns-detection

# Build the Lambda deployment package
./scripts/package.sh

# Upload to S3
aws s3 cp dist/dangling-dns-detection.zip s3://YOUR_BUCKET/

# Deploy the CloudFormation stack
aws cloudformation deploy \
  --template-file infrastructure/template.yaml \
  --stack-name dangling-dns-detection \
  --parameter-overrides \
      LambdaCodeS3Bucket=YOUR_BUCKET \
      EvaluationFrequency=TwentyFour_Hours \
  --capabilities CAPABILITY_NAMED_IAM

The stack creates an AWS Config custom rule that runs on your specified schedule (default: every 24 hours), evaluating all CNAME records and reporting compliance status.

Mitigating the effects

Mitigating subdomain takeover requires both preventive procedures and responsive capabilities.

Prevention: Standard operating procedure

The most effective mitigation is a standard operating procedure for resource deprovisioning that ensures DNS records are removed before the underlying resource:

  1. Within your DNS zone, delete the CNAME record that points to the fully qualified domain name (FQDN) of the resource that you plan to deprovision.
  2. Wait for the DNS TTL to expire before deleting the resource. DNS resolvers cache records for the duration of the TTL (for example, a TTL of 3600 means resolvers may serve the old record for up to one hour). If you delete the resource before the TTL expires, a threat actor could claim the resource name while cached CNAME entries are still directing traffic to it.
  3. Deprovision the resource that you no longer want to use.
  4. Run a DNS check of the CNAME record that you removed to verify that the resource is no longer resolving.

Key principle: Always delete DNS first, wait for the TTL to expire, then delete the resource. This order eliminates the window where a dangling record could be exploited.

Prevention: S3 account regional namespaces

As mentioned earlier, AWS introduced account regional namespaces for Amazon S3 general purpose buckets in March 2026. While this is a meaningful step toward mitigating the S3-specific takeover vector, there are important operational limitations to be aware of:

Existing buckets are unaffected. Buckets already created in the global namespace cannot be migrated to an account regional namespace. The bucket names remain globally unique and claimable by anyone if the bucket is deleted.

Global namespace is still the default. When creating a new bucket through the console, CLI, or SDK, the global namespace remains the default selection. Users who aren’t aware of the new option will continue creating globally-scoped buckets.

Existing IaC templates require updates. Existing infrastructure-as-code templates (CloudFormation, CDK, Terraform) that don’t explicitly opt in to the account regional namespace will continue provisioning buckets in the global namespace. For CloudFormation, this means setting the BucketNamespace property to account-regional. For other IaC tools, consult their documentation for the equivalent configuration. Organizations need to audit and update their templates to opt in.

For these reasons, the dangling DNS detection approach described in this post remains critical – particularly for organizations with existing S3 infrastructure, and for CloudFront, and Elastic Beanstalk resources where no equivalent namespace scoping exists.

Response: Notification and remediation

When a dangling DNS record is detected, the reference solution described in the Detection section automatically creates a HIGH severity finding in AWS Security Hub and reports the CNAME record as NON_COMPLIANT in AWS Config. If you provide an SNS topic ARN during deployment, the solution also sends notifications to alert your security or operations team via email, Slack, or other channels. For production environments, consider a human-in-the-loop workflow where these notifications are reviewed by a team member who approves the DNS record deletion before it’s executed. This prevents accidental deletion of legitimate records during transient issues.

The reference solution also includes a CloudWatch dashboard for tracking compliance status and evaluation metrics over time, giving your team ongoing visibility into DNS health across your hosted zones.

Note: Fully automated remediation (auto-deleting DNS records) carries risk – a false positive could disrupt legitimate services. We recommend starting with detection and notification, then evaluating automation based on your detection accuracy and operational maturity.

Conclusion

Subdomain takeover is a preventable misconfiguration that can have significant impact on your organization. A layered defense approach provides the best protection:

Prevention: Implement a standard operating procedure that deletes DNS records before deprovisioning the underlying resource.

Detection: Use AWS Config custom rules to proactively identify CNAME records pointing to resources that no longer exist in your account.

Response: Configure notifications through SNS or Security Hub so your team can respond quickly when dangling records are detected.

Monitoring: Maintain ongoing visibility through CloudWatch dashboards to track DNS health and compliance status.

The key insight is that good DNS hygiene – knowing when your CNAME records point to a nonexistent resource – is your first line of defense. Automated detection through AWS Config provides a safety net when operational procedures fail. And if you detect an issue, having a playbook ready to enact your response can lower the impact and your mean time to recovery.

If you have feedback about this post, submit comments in the Comments section below.


Matt Gurr

Matthew Gurr

Matthew is the Senior Incident Response lead in the Asia-Pacific region for the AWS Customer Incident Response Team (AWS CIRT). He has a passion for helping customers proactively prepare for a security event. In his spare time, he enjoys cycling, music, and reading.

Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect at AWS leading the Infrastructure Security and Compliance Technical Field Communities. He drives security architecture for enterprise customers across financial services, healthcare, and retail, specializing in cloud security transformation and regulatory compliance frameworks. Before AWS, Luis architected security solutions in hybrid cloud environments.

Geoff Sweet

Geoff Sweet

Geoff has been in industry since the late 1990s. He began his career in electrical engineering. Starting in IT during the dot-com boom, he has held a variety of diverse roles, such as systems architect, network architect, and, for the past several years, security architect. Geoff specializes in infrastructure security.

Ariam Michael

Ariam Michael

Ariam is a Solutions Architect at AWS. She has supported various customers in the Worldwide Public Sector, specifically SLG and Federal Civilian customers. She is passionate about security, specifically Data Protection helping customers implement encryption and best practices.

How to use AWS Transfer Family and GuardDuty for malware protection

Post Syndicated from James Abbott original https://aws.amazon.com/blogs/security/how-to-use-aws-transfer-family-and-guardduty-for-malware-protection/

Organizations often need to securely share files with external parties over the internet. Allowing public access to a file transfer server exposes the organization to potential threats, such as malware-infected files uploaded by threat actors or inadvertently by genuine users. To mitigate this risk, companies can take steps to help make sure that files received through public channels are scanned for malware before processing.

This post demonstrates how to use AWS Transfer Family and Amazon GuardDuty to scan files uploaded through a secure FTP (SFTP) server for malware as part of an overall transfer workflow. For readers who might have read an earlier blog post on this topic, the key difference is that this solution is fully managed and doesn’t require the deployment of compute resources. GuardDuty automatically updates malware signatures every 15 minutes instead of using a container image for scanning, avoiding the need for manual patching to keep the signatures up to date.

Prerequisites

To deploy the solution in this post, you will need:

  • An AWS account: You need access to AWS to deploy this solution. If you don’t have an account that you can use, see Start building on AWS today.
  • AWS CLI: Install and configure the AWS Command Line Interface (AWS CLI) to be authenticated to your AWS account. Set up the environment variables for your AWS account using the access token and secret access key for your environment.
  • Git: You will use Git to pull down the example code from GitHub.
  • Terraform: You’ll use Terraform to run the automation. Follow the Terraform installation instructions to download and set up Terraform.

Solution overview

This solution uses Transfer Family and GuardDuty. Transfer Family provides a secure file transfer service that you can use to set up an SFTP server, and GuardDuty is an intelligent threat detection service. GuardDuty monitors for malicious activity and anomalous behavior to protect AWS accounts, workloads, and data. At a high level, the solution uses the following steps:

  • A user uploads a file through a Transfer Family SFTP server.
  • A Transfer Family managed workflow invokes AWS Lambda to execute an AWS Step Functions workflow.
    • The workflow begins only after a successful file upload.
    • Partial uploads to the SFTP server will invoke an error handling Lambda function to report a partial upload error.
  • A step function state machine invokes a Lambda function to move uploaded files to an Amazon Simple Storage Service (Amazon S3) bucket for processing and then starts scanning using GuardDuty.
  • The GuardDuty scan result is sent as a callback to the step function.
  • Infected files are moved or cleaned.
  • The workflow sends the user the results through an Amazon Simple Notification Service (Amazon SNS) topic. This can be a notification of an error or malicious upload during the scan or notification of a successful upload and a clean scan for further processing.

Solution architecture and walkthrough

The solution uses GuardDuty Malware Protection for S3 to scan newly uploaded objects to the S3 bucket. You can use this feature of GuardDuty to set up a malware protection plan for an S3 bucket at the bucket level or to watch for specific object prefixes.

Figure 1: Solution architecture

Figure 1: Solution architecture

The following steps (shown in Figure 1) describe the workflow for this solution starting from the point the file is uploaded until it’s scanned and marked as safe or as infected, leading to subsequent steps that can be customized based on your use case.

  1. A file is uploaded using the SFTP protocol through Transfer Family.
  2. If the file is successfully uploaded, Transfer Family uploads the file to the S3 bucket called Unscanned and the Managed Workflow Complete workflow is triggered. This is the workflow used to handle successful uploads and invokes the Step Function Invoker Lambda function.
  3. The Step Function Invoker starts the state machine and kicks off the first step in the process by invoking the GuardDuty – Scan Lambda function.
  4. The GuardDuty – Scan function moves the file to the Processing bucket. This is the bucket from which the files will be scanned.
  5. When an object upload activity is detected, GuardDuty automatically scans the object. In this implementation, a malware protection plan is created for the Processing bucket.
  6. When a scan completes, GuardDuty publishes the scan result to Amazon EventBridge.
  7. An EventBridge rule has been created to invoke a Lambda Callback function whenever a scan event has completed. EventBridge will invoke the function with an event that contains the scan results. See Monitoring S3 object scans with Amazon EventBridge for an example.
  8. The Lambda Callback function notifies the GuardDuty – Scan task using the callback task integration pattern. The results of the GuardDuty scan are returned to the GuardDuty – Scan function and these results are passed to the Move File task.
  9. If the result is a clean scan with no threats detected, the Move File task will place the file in the Clean S3 bucket, indicating that the file is successfully scanned and safe for further processing.
  10. At this point, the Move File function publishes a notification to the Success SNS topic to notify the subscribers.
  11. If the result indicates that the file is malicious, the Move File function will instead move the file to the Quarantine S3 bucket for further investigation. The function will also delete the file from the Processing bucket and publish a notification in the Error topic in SNS to notify the user of a potential malicious file being uploaded.
  12. If the file upload is unsuccessful and the file isn’t fully uploaded, then Transfer Family will trigger the Managed Workflow Partial workflow.
  13. Managed Workflow Partial is an error handling workflow and invokes the Error Publisher function, which is used for reporting errors that occur anywhere in the workflow.
  14. The Error Publisher function identifies the type of error—whether it’s because of the partial upload or an issue elsewhere in the workflow—and sets the error status accordingly. It will then publish an error message to Error Topic in SNS.
  15. The GuardDuty – Scan task has a timeout to make sure that an event is published to Error Topic to prompt a manual intervention to investigate further if the file isn’t successfully scanned. If the GuardDuty – Scan task fails, the Error clean up Lambda function is invoked.

Finally, there’s an S3 Lifecycle policy attached to the Processing bucket. This is to make sure that no file is left in the Processing bucket for more than one day.

Code repository

The GitHub AWS-samples repository has a sample implementation developed using Terraform and Python-based Lambda functions to implement this solution. The same solution can also be implemented using AWS CloudFormation. The code has the components needed to deploy the entire workflow to demonstrate the abilities of Transfer Family and the GuardDuty malware protection plan.

Install the solution

Use the following steps to deploy this solution to your test environment.

  1. Clone the repository to your working directory using Git.
  2. Navigate to the root directory of your cloned project directory.
  3. Update the terraform locals.tf file with the values of your choice for the S3 bucket names, SFTP server names, and other variables.
  4. Run terraform plan.
  5. If everything looks good, run a terraform apply and enter yes to create the resources.

Clean up

After testing and exploring the solution, it’s important to clean up the resources you created to avoid incurring unnecessary costs. To delete the resources created by this solution, navigate to the root directory of your cloned project and run the following command:

terraform destroy

This command will remove the resources created by Terraform, including the SFTP server, S3 buckets, Lambda functions, and other components. Confirm the deletion by entering yes when prompted.

Conclusion

By using the approach outlined in the post, you can make sure that the files received over SFTP and uploaded to your S3 bucket are scanned for threats and are safe for further processing. The solution reduces the exposure surface by making sure that public uploads are scanned in a safe environment before they’re sent to other components of your system.

If you have feedback about this post, submit comments in the Comments section below.

James Abbott

James Abbott

James is a Principal Solutions Architect at AWS, working in Global Financial Services. When not in the office he enjoys mountain biking in North Carolina.

Santhosh Srinivasan

Santhosh Srinivasan

Santhosh is a Sr. Cloud Application Architect with the Professional Services team at AWS. He specializes in building and modernizing large scale enterprise applications in the cloud with a focus on the financial services industry.

Suhas Pasricha

Suhas Pasricha

Suhas is a Cloud Infrastructure Architect in the AWS Professional Services team. He has a background in web development and infrastructure automation. At Amazon, he has been helping customers set up and operate an enterprise-wide landing zone and cloud environment. In his spare time, he likes to read and play video games.

Mask and redact sensitive data published to Amazon SNS using managed and custom data identifiers

Post Syndicated from Otavio Ferreira original https://aws.amazon.com/blogs/security/mask-and-redact-sensitive-data-published-to-amazon-sns-using-managed-and-custom-data-identifiers/

Today, we’re announcing a new capability for Amazon Simple Notification Service (Amazon SNS) message data protection. In this post, we show you how you can use this new capability to create custom data identifiers to detect and protect domain-specific sensitive data, such as your company’s employee IDs. Previously, you could only use managed data identifiers to detect and protect common sensitive data, such as names, addresses, and credit card numbers.

Overview

Amazon SNS is a serverless messaging service that provides topics for push-based, many-to-many messaging for decoupling distributed systems, microservices, and event-driven serverless applications. As applications become more complex, it can become challenging for topic owners to manage the data flowing through their topics. These applications might inadvertently start sending sensitive data to topics, increasing regulatory risk. To mitigate the risk, you can use message data protection to protect sensitive application data using built-in, no-code, scalable capabilities.

To discover and protect data flowing through SNS topics with message data protection, you can associate data protection policies to your topics. Within these policies, you can write statements that define which types of sensitive data you want to discover and protect. Within each policy statement, you can then define whether you want to act on data flowing inbound to an SNS topic or outbound to an SNS subscription, the AWS accounts or specific AWS Identity and Access Management (IAM) principals the statement applies to, and the actions you want to take on the sensitive data found.

Now, message data protection provides three actions to help you protect your data. First, the audit operation reports on the amount of sensitive data found. Second, the deny operation helps prevent the publishing or delivery of payloads that contain sensitive data. Third, the de-identify operation can mask or redact the sensitive data detected. These no-code operations can help you adhere to a variety of compliance regulations, such as Health Insurance Portability and Accountability Act (HIPAA), Federal Risk and Authorization Management Program (FedRAMP), General Data Protection Regulation (GDPR), and Payment Card Industry Data Security Standard (PCI DSS).

This message data protection feature coexists with the message data encryption feature in SNS, both contributing to an enhanced security posture of your messaging workloads.

Managed and custom data identifiers

After you add a data protection policy to your SNS topic, message data protection uses pattern matching and machine learning models to scan your messages for sensitive data, then enforces the data protection policy in real time. The types of sensitive data are referred to as data identifiers. These data identifiers can be either managed by Amazon Web Services (AWS) or custom to your domain.

Managed data identifiers (MDI) are organized into five categories:

In a data protection policy statement, you refer to a managed data identifier using its Amazon Resource Name (ARN), as follows:

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Statement": [{
        "DataIdentifier": [
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "..."
    }]
}

Custom data identifiers (CDI), on the other hand, enable you to define custom regular expressions in the data protection policy itself, then refer to them from policy statements. Using custom data identifiers, you can scan for business-specific sensitive data, which managed data identifiers can’t. For example, you can use a custom data identifier to look for company-specific employee IDs in SNS message payloads. Internally, SNS has guardrails to make sure custom data identifiers are safe and that they add only low single-digit millisecond latency to message processing.

In a data protection policy statement, you refer to a custom data identifier using only the name that you have given it, as follows:

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "DataIdentifier": [
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber",
            "MyCompanyEmployeeId"
        ],
        "..."
    }]
}

Note that custom data identifiers can be used in conjunction with managed data identifiers, as part of the same data protection policy statement. In the preceding example, both MyCompanyEmployeeId and CreditCardNumber are in scope.

For more information, see Data Identifiers, in the SNS Developer Guide.

Inbound and outbound data directions

In addition to the DataIdentifier property, each policy statement also sets the DataDirection property (whose value can be either Inbound or Outbound) as well as the Principal property (whose value can be any combination of AWS accounts, IAM users, and IAM roles).

When you use message data protection for data de-identification and set DataDirection to Inbound, instances of DataIdentifier published by the Principal are masked or redacted before the payload is ingested into the SNS topic. This means that every endpoint subscribed to the topic receives the same modified payload.

When you set DataDirection to Outbound, on the other hand, the payload is ingested into the SNS topic as-is. Then, instances of DataIdentifier are either masked, redacted, or kept as-is for each subscribing Principal in isolation. This means that each endpoint subscribed to the SNS topic might receive a different payload from the topic, with different sensitive data de-identified, according to the data access permissions of its Principal.

The following snippet expands the example data protection policy to include the DataDirection and Principal properties.

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "DataIdentifier": [
            "MyCompanyEmployeeId",
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "DataDirection": "Outbound",
        "Principal": [ "arn:aws:iam::123456789012:role/ReportingApplicationRole" ],
        "..."
    }]
}

In this example, ReportingApplicationRole is the authenticated IAM principal that called the SNS Subscribe API at subscription creation time. For more information, see How do I determine the IAM principals for my data protection policy? in the SNS Developer Guide.

Operations for data de-identification

To complete the policy statement, you need to set the Operation property, which informs the SNS topic of the action that it should take when it finds instances of DataIdentifer in the outbound payload.

The following snippet expands the data protection policy to include the Operation property, in this case using the Deidentify object, which in turn supports masking and redaction.

{
    "Name": "__example_data_protection_policy",
    "Description": "This policy protects sensitive data in expense reports",
    "Version": "2021-06-01",
    "Configuration": {
        "CustomDataIdentifier": [{
            "Name": "MyCompanyEmployeeId", "Regex": "EID-\d{9}-US"
        }]
    },
    "Statement": [{
        "Principal": [
            "arn:aws:iam::123456789012:role/ReportingApplicationRole"
        ],
        "DataDirection": "Outbound",
        "DataIdentifier": [
            "MyCompanyEmployeeId",
            "arn:aws:dataprotection::aws:data-identifier/CreditCardNumber"
        ],
        "Operation": { "Deidentify": { "MaskConfig": { "MaskWithCharacter": "#" } } }
    }]
}

In this example, the MaskConfig object instructs the SNS topic to mask instances of CreditCardNumber in Outbound messages to subscriptions created by ReportingApplicationRole, using the MaskWithCharacter value, which in this case is the hash symbol (#). Alternatively, you could have used the RedactConfig object instead, which would have instructed the SNS topic to simply cut the sensitive data off the payload.

The following snippet shows how the outbound payload is masked, in real time, by the SNS topic.

// original message published to the topic:
My credit card number is 4539894458086459

// masked message delivered to subscriptions created by ReportingApplicationRole:
My credit card number is ################

For more information, see Data Protection Policy Operations, in the SNS Developer Guide.

Applying data de-identification in a use case

Consider a company where managers use an internal expense report management application where expense reports from employees can be reviewed and approved. Initially, this application depended only on an internal payment application, which in turn connected to an external payment gateway. However, this workload eventually became more complex, because the company started also paying expense reports filed by external contractors. At that point, the company built a mobile application that external contractors could use to view their approved expense reports. An important business requirement for this mobile application was that specific financial and PII data needed to be de-identified in the externally displayed expense reports. Specifically, both the credit card number used for the payment and the internal employee ID that approved the payment had to be masked.

Figure 1: Expense report processing application

Figure 1: Expense report processing application

To distribute the approved expense reports to both the payment application and the reporting application that backed the mobile application, the company used an SNS topic with a data protection policy. The policy has only one statement, which masks credit card numbers and employee IDs found in the payload. This statement applies only to the IAM role that the company used for subscribing the AWS Lambda function of the reporting application to the SNS topic. This access permission configuration enabled the Lambda function from the payment application to continue receiving the raw data from the SNS topic.

The data protection policy from the previous section addresses this use case. Thus, when a message representing an expense report is published to the SNS topic, the Lambda function in the payment application receives the message as-is, whereas the Lambda function in the reporting application receives the message with the financial and PII data masked.

Deploying the resources

You can apply a data protection policy to an SNS topic using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK, or AWS CloudFormation.

To automate the provisioning of the resources and the data protection policy of the example expense management use case, we’re going to use CloudFormation templates. You have two options for deploying the resources:

Deploy using the individual CloudFormation templates in sequence

  1. Prerequisites template: This first template provisions two IAM roles with a managed policy that enables them to create SNS subscriptions and configure the subscriber Lambda functions. You will use these provisioned IAM roles in steps 3 and 4 that follow.
  2. Topic owner template: The second template provisions the SNS topic along with its access policy and data protection policy.
  3. Payment subscriber template: The third template provisions the Lambda function and the corresponding SNS subscription that comprise of the Payment application stack. When prompted, select the PaymentApplicationRole in the Permissions panel before running the template. Moreover, the CloudFormation console will require you to acknowledge that a CloudFormation transform might require access capabilities.
  4. Reporting subscriber template: The final template provisions the Lambda function and the SNS subscription that comprise of the Reporting application stack. When prompted, select the ReportingApplicationRole in the Permissions panel, before running the template. Moreover, the CloudFormation console will require, once again, that you acknowledge that a CloudFormation transform might require access capabilities.
Figure 2: Select IAM role

Figure 2: Select IAM role

Now that the application stacks have been deployed, you’re ready to start testing.

Testing the data de-identification operation

Use the following steps to test the example expense management use case.

  1. In the Amazon SNS console, select the ApprovalTopic, then choose to publish a message to it.
  2. In the SNS message body field, enter the following message payload, representing an external contractor expense report, then choose to publish this message:
    {
        "expense": {
            "currency": "USD",
            "amount": 175.99,
            "category": "Office Supplies",
            "status": "Approved",
            "created_at": "2023-10-17T20:03:44+0000",
            "updated_at": "2023-10-19T14:21:51+0000"
        },
        "payment": {
            "credit_card_network": "Visa",
            "credit_card_number": "4539894458086459"
        },
        "reviewer": {
            "employee_id": "EID-123456789-US",
            "employee_location": "Seattle, USA"
        },
        "contractor": {
            "employee_id": "CID-000012348-CA",
            "employee_location": "Vancouver, CAN"
        }
    }
    

  3. In the CloudWatch console, select the log group for the PaymentLambdaFunction, then choose to view its latest log stream. Now look for the log stream entry that shows the message payload received by the Lambda function. You will see that no data has been masked in this payload, as the payment application requires raw financial data to process the credit card transaction.
  4. Still in the CloudWatch console, select the log group for the ReportingLambdaFunction, then choose to view its latest log stream. Now look for the log stream entry that shows the message payload received by this Lambda function. You will see that the values for properties credit_card_number and employee_id have been masked, protecting the financial data from leaking into the external reporting application.
    {
        "expense": {
            "currency": "USD",
            "amount": 175.99,
            "category": "Office Supplies",
            "status": "Approved",
            "created_at": "2023-10-17T20:03:44+0000",
            "updated_at": "2023-10-19T14:21:51+0000"
        },
        "payment": {
            "credit_card_network": "Visa",
            "credit_card_number": "################"
        },
        "reviewer": {
            "employee_id": "################",
            "employee_location": "Seattle, USA"
        },
        "contractor": {
            "employee_id": "CID-000012348-CA",
            "employee_location": "Vancouver, CAN"
        }
    }
    

As shown, different subscribers received different versions of the message payload, according to their sensitive data access permissions.

Cleaning up the resources

After testing, avoid incurring usage charges by deleting the resources that you created. Open the CloudFormation console and delete the four CloudFormation stacks that you created during the walkthrough.

Conclusion

This post showed how you can use Amazon SNS message data protection to discover and protect sensitive data published to or delivered from your SNS topics. The example use case shows how to create a data protection policy that masks messages delivered to specific subscribers if the payloads contain financial or personally identifiable information.

For more details, see message data protection in the SNS Developer Guide. For information on costs, see SNS pricing.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Otavio-Ferreira-author

Otavio Ferreira

Otavio is the GM for Amazon SNS, and has been leading the service since 2016, responsible for software engineering, product management, technical program management, and technical operations. Otavio has spoken at AWS conferences—AWS re:Invent and AWS Summit—and written a number of articles for the AWS Compute and AWS Security blogs.

How to add notifications and manual approval to an AWS CDK Pipeline

Post Syndicated from Jehu Gray original https://aws.amazon.com/blogs/devops/how-to-add-notifications-and-manual-approval-to-an-aws-cdk-pipeline/

A deployment pipeline typically comprises several stages such as dev, test, and prod, which ensure that changes undergo testing before reaching the production environment. To improve the reliability and stability of release processes, DevOps teams must review Infrastructure as Code (IaC) changes before applying them in production. As a result, implementing a mechanism for notification and manual approval that grants stakeholders improved access to changes in their release pipelines has become a popular practice for DevOps teams.

Notifications keep development teams and stakeholders informed in real-time about updates and changes to deployment status within release pipelines. Manual approvals establish thresholds for transitioning a change from one stage to the next in the pipeline. They also act as a guardrail to mitigate risks arising from errors and rework because of faulty deployments.

Please note that manual approvals, as described in this post, are not a replacement for the use of automation. Instead, they complement automated checks within the release pipeline.

In this blog post, we describe how to set up notifications and add a manual approval stage to AWS Cloud Development Kit (AWS CDK) Pipeline.

Concepts

CDK Pipeline

CDK Pipelines is a construct library for painless continuous delivery of CDK applications. CDK Pipelines can automatically build, test, and deploy changes to CDK resources. CDK Pipelines are self-mutating which means as application stages or stacks are added, the pipeline automatically reconfigures itself to deploy those new stages or stacks. Pipelines need only be manually deployed once, afterwards, the pipeline keeps itself up to date from the source code repository by pulling the changes pushed to the repository.

Notifications

Adding notifications to a pipeline provides visibility to changes made to the environment by utilizing the NotificationRule construct. You can also use this rule to notify pipeline users of important changes, such as when a pipeline starts execution. Notification rules specify both the events and the targets, such as Amazon Simple Notification Service (Amazon SNS) topic or AWS Chatbot clients configured for Slack which represents the nominated recipients of the notifications. An SNS topic is a logical access point that acts as a communication channel while Chatbot is an AWS service that enables DevOps and software development teams to use messaging program chat rooms to monitor and respond to operational events.

Manual Approval

In a CDK pipeline, you can incorporate an approval action at a specific stage, where the pipeline should pause, allowing a team member or designated reviewer to manually approve or reject the action. When an approval action is ready for review, a notification is sent out to alert the relevant parties. This combination of notifications and approvals ensures timely and efficient decision-making regarding crucial actions within the pipeline.

Solution Overview

The solution explains a simple web service that is comprised of an AWS Lambda function that returns a static web page served by Amazon API Gateway. Since Continuous Deployment and Continuous Integration (CI/CD) are important components to most web projects, the team implements a CDK Pipeline for their web project.

There are two important stages in this CDK pipeline; the Pre-production stage for testing and the Production stage, which contains the end product for users.

The flow of the CI/CD process to update the website starts when a developer pushes a change to the repository using their Integrated Development Environment (IDE). An Amazon CloudWatch event triggers the CDK Pipeline. Once the changes reach the pre-production stage for testing, the CI/CD process halts. This is because a manual approval gate is between the pre-production and production stages. So, it becomes a stakeholder’s responsibility to review the changes in the pre-production stage before approving them for production. The pipeline includes an SNS notification that notifies the stakeholder whenever the pipeline requires manual approval.

After approving the changes, the CI/CD process proceeds to the production stage and the updated version of the website becomes available to the end user. If the approver rejects the changes, the process ends at the pre-production stage with no impact to the end user.

The following diagram illustrates the solution architecture.


This diagram shows the CDK pipeline process in the solution and how applications or updates are deployed using AWS Lambda Function to end users.

Figure 1. This image shows the CDK pipeline process in our solution and how applications or updates are deployed using AWS Lambda Function to end users.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Add notification to the pipeline

In this tutorial, perform the following steps:

  • Add the import statements for AWS CodeStar notifications and SNS to the import section of the pipeline stack py
import aws_cdk.aws_codestarnotifications as notifications
import aws_cdk.pipelines as pipelines
import aws_cdk.aws_sns as sns
import aws_cdk.aws_sns_subscriptions as subs
  • Ensure the pipeline is built by calling the ‘build pipeline’ function.

pipeline.build_pipeline()

  • Create an SNS topic.

topic = sns.Topic(self, "MyTopic1")

  • Add a subscription to the topic. This specifies where the notifications are sent (Add the stakeholders’ email here).

topic.add_subscription(subs.EmailSubscription("[email protected]"))

  • Define a rule. This contains the source for notifications, the event trigger, and the target .

rule = notifications.NotificationRule(self, "NotificationRule", )

  • Assign the source the value pipeline.pipeline The first pipeline is the name of the CDK pipeline(variable) and the .pipeline is to show it is a pipeline(function).

source=pipeline.pipeline,

  • Define the events to be monitored. Specify notifications for when the pipeline starts, when it fails, when the execution succeeds, and finally when manual approval is needed.
events=["codepipeline-pipeline-pipeline-execution-started", "codepipeline-pipeline-pipeline-execution-failed","codepipeline-pipeline-pipeline-execution-succeeded", 
"codepipeline-pipeline-manual-approval-needed"],
  • For the complete list of supported event types for pipelines, see here
  • Finally, add the target. The target here is the topic created previously.

targets=[topic]

The combination of all the steps becomes:

pipeline.build_pipeline()
topic = sns.Topic(self, "MyTopic1")
topic.add_subscription(subs.EmailSubscription("[email protected]"))
rule = notifications.NotificationRule(self, "NotificationRule",
source=pipeline.pipeline,
events=["codepipeline-pipeline-pipeline-execution-started", "codepipeline-pipeline-pipeline-execution-failed","codepipeline-pipeline-pipeline-execution-succeeded", 
"codepipeline-pipeline-manual-approval-needed"],
targets=[topic]
)

Adding Manual Approval

  • Add the ManualApprovalStep import to the aws_cdk.pipelines import statement.
from aws_cdk.pipelines import (
CodePipeline,
CodePipelineSource,
ShellStep,
ManualApprovalStep
)
  • Add the ManualApprovalStep to the production stage. The code must be added to the add_stage() function.
 prod = WorkshopPipelineStage(self, "Prod")
        prod_stage = pipeline.add_stage(prod,
            pre = [ManualApprovalStep('PromoteToProduction')])

When a stage is added to a pipeline, you can specify the pre and post steps, which are arbitrary steps that run before or after the contents of the stage. You can use them to add validations like manual or automated gates to the pipeline. It is recommended to put manual approval gates in the set of pre steps, and automated approval gates in the set of post steps. So, the manual approval action is added as a pre step that runs after the pre-production stage and before the production stage .

  • The final version of the pipeline_stack.py becomes:
from constructs import Construct
import aws_cdk as cdk
import aws_cdk.aws_codestarnotifications as notifications
import aws_cdk.aws_sns as sns
import aws_cdk.aws_sns_subscriptions as subs
from aws_cdk import (
    Stack,
    aws_codecommit as codecommit,
    aws_codepipeline as codepipeline,
    pipelines as pipelines,
    aws_codepipeline_actions as cpactions,
    
)
from aws_cdk.pipelines import (
    CodePipeline,
    CodePipelineSource,
    ShellStep,
    ManualApprovalStep
)


class WorkshopPipelineStack(cdk.Stack):
    def __init__(self, scope: Construct, id: str, **kwargs) -> None:
        super().__init__(scope, id, **kwargs)
        
        # Creates a CodeCommit repository called 'WorkshopRepo'
        repo = codecommit.Repository(
            self, "WorkshopRepo", repository_name="WorkshopRepo",
            
        )
        
        #Create the Cdk pipeline
        pipeline = pipelines.CodePipeline(
            self,
            "Pipeline",
            
            synth=pipelines.ShellStep(
                "Synth",
                input=pipelines.CodePipelineSource.code_commit(repo, "main"),
                commands=[
                    "npm install -g aws-cdk",  # Installs the cdk cli on Codebuild
                    "pip install -r requirements.txt",  # Instructs Codebuild to install required packages
                    "npx cdk synth",
                ]
                
            ),
        )

        
         # Create the Pre-Prod Stage and its API endpoint
        deploy = WorkshopPipelineStage(self, "Pre-Prod")
        deploy_stage = pipeline.add_stage(deploy)
    
        deploy_stage.add_post(
            
            pipelines.ShellStep(
                "TestViewerEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": deploy.hc_viewer_url
                },
                commands=["curl -Ssf $ENDPOINT_URL"],
            )
    
        
        )
        deploy_stage.add_post(
            pipelines.ShellStep(
                "TestAPIGatewayEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": deploy.hc_endpoint
                },
                commands=[
                    "curl -Ssf $ENDPOINT_URL",
                    "curl -Ssf $ENDPOINT_URL/hello",
                    "curl -Ssf $ENDPOINT_URL/test",
                ],
            )
            
        )
        
        # Create the Prod Stage with the Manual Approval Step
        prod = WorkshopPipelineStage(self, "Prod")
        prod_stage = pipeline.add_stage(prod,
            pre = [ManualApprovalStep('PromoteToProduction')])
        
        prod_stage.add_post(
            
            pipelines.ShellStep(
                "ViewerEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": prod.hc_viewer_url
                },
                commands=["curl -Ssf $ENDPOINT_URL"],
                
            )
            
        )
        prod_stage.add_post(
            pipelines.ShellStep(
                "APIGatewayEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": prod.hc_endpoint
                },
                commands=[
                    "curl -Ssf $ENDPOINT_URL",
                    "curl -Ssf $ENDPOINT_URL/hello",
                    "curl -Ssf $ENDPOINT_URL/test",
                ],
            )
            
        )
        
        # Create The SNS Notification for the Pipeline
        
        pipeline.build_pipeline()
        
        topic = sns.Topic(self, "MyTopic")
        topic.add_subscription(subs.EmailSubscription("[email protected]"))
        rule = notifications.NotificationRule(self, "NotificationRule",
            source = pipeline.pipeline,
            events = ["codepipeline-pipeline-pipeline-execution-started", "codepipeline-pipeline-pipeline-execution-failed", "codepipeline-pipeline-manual-approval-needed", "codepipeline-pipeline-manual-approval-succeeded"],
            targets=[topic]
            )


When a commit is made with git commit -am "Add manual Approval" and changes are pushed with git push, the pipeline automatically self-mutates to add the new approval stage.

Now when the developer pushes changes to update the build environment or the end user application, the pipeline execution stops at the point where the approval action was added. The pipeline won’t resume unless a manual approval action is taken.

Image showing the CDK pipeline with the added Manual Approval action on the AWS Management Console

Figure 2. This image shows the pipeline with the added Manual Approval action.

Since there is a notification rule that includes the approval action, an email notification is sent with the pipeline information and approval status to the stakeholder(s) subscribed to the SNS topic.

Image showing the SNS email notification sent when the pipeline starts

Figure 3. This image shows the SNS email notification sent when the pipeline starts.

After pushing the updates to the pipeline, the reviewer or stakeholder can use the AWS Management Console to access the pipeline to approve or deny changes based on their assessment of these changes. This process helps eliminate any potential issues or errors and ensures only changes deemed relevant are made.

Image showing the review action on the AWS Management Console that gives the stakeholder the ability to approve or reject any changes.

Figure 4. This image shows the review action that gives the stakeholder the ability to approve or reject any changes. 

If a reviewer rejects the action, or if no approval response is received within seven days of the pipeline stopping for the review action, the pipeline status is “Failed.”

Image showing when a stakeholder rejects the action

Figure 5. This image depicts when a stakeholder rejects the action.

If a reviewer approves the changes, the pipeline continues its execution.

Image showing when a stakeholder approves the action

Figure 6. This image depicts when a stakeholder approves the action.

Considerations

It is important to consider any potential drawbacks before integrating a manual approval process into a CDK pipeline. one such consideration is its implementation may delay the delivery of updates to end users. An example of this is business hours limitation. The pipeline process might be constrained by the availability of stakeholders during business hours. This can result in delays if changes are made outside regular working hours and require approval when stakeholders are not immediately accessible.

Clean up

To avoid incurring future charges, delete the resources. Use cdk destroy via the command line to delete the created stack.

Conclusion

Adding notifications and manual approval to CDK Pipelines provides better visibility and control over the changes made to the pipeline environment. These features ideally complement the existing automated checks to ensure that all updates are reviewed before deployment. This reduces the risk of potential issues arising from bugs or errors. The ability to approve or deny changes through the AWS Management Console makes the review process simple and straightforward. Additionally, SNS notifications keep stakeholders updated on the status of the pipeline, ensuring a smooth and seamless deployment process.

Jehu Gray

Jehu Gray is an Enterprise Solutions Architect at Amazon Web Services where he helps customers design solutions that fits their needs. He enjoys exploring whats possible with IaC such as CDK.

Abiola Olanrewaju

Abiola Olanrewaju is an Enterprise Solutions Architect at Amazon Web Services where he helps customers design and implement scalable solutions that drive business outcomes. He has a keen interest in Data Analytics, Security and Automation.

Serge Poueme

Serge Poueme is a Solutions Architect on the AWS for Games Team. He started his career as a software development engineer and enjoys building new products. At AWS, Serge focuses on improving Builders Experience for game developers and optimize servers hosting using Containers. When he is not working he enjoys playing Far Cry or Fifa on his XBOX

How to Receive Alerts When Your IAM Configuration Changes

Post Syndicated from Dylan Souvage original https://aws.amazon.com/blogs/security/how-to-receive-alerts-when-your-iam-configuration-changes/

July 27, 2023: This post was originally published February 5, 2015, and received a major update July 31, 2023.


As an Amazon Web Services (AWS) administrator, it’s crucial for you to implement robust protective controls to maintain your security configuration. Employing a detective control mechanism to monitor changes to the configuration serves as an additional safeguard in case the primary protective controls fail. Although some changes are expected, you might want to review unexpected changes or changes made by a privileged user. AWS Identity and Access Management (IAM) is a service that primarily helps manage access to AWS services and resources securely. It does provide detailed logs of its activity, but it doesn’t inherently provide real-time alerts or notifications. Fortunately, you can use a combination of AWS CloudTrail, Amazon EventBridge, and Amazon Simple Notification Service (Amazon SNS) to alert you when changes are made to your IAM configuration. In this blog post, we walk you through how to set up EventBridge to initiate SNS notifications for IAM configuration changes. You can also have SNS push messages directly to ticketing or tracking services, such as Jira, Service Now, or your preferred method of receiving notifications, but that is not discussed here.

In any AWS environment, many activities can take place at every moment. CloudTrail records IAM activities, EventBridge filters and routes event data, and Amazon SNS provides notification functionality. This post will guide you through identifying and setting alerts for IAM changes, modifications in authentication and authorization configurations, and more. The power is in your hands to make sure you’re notified of the events you deem most critical to your environment. Here’s a quick overview of how you can invoke a response, shown in Figure 1.

Figure 1: Simple architecture diagram of actors and resources in your account and the process for sending notifications through IAM, CloudTrail, EventBridge, and SNS.

Figure 1: Simple architecture diagram of actors and resources in your account and the process for sending notifications through IAM, CloudTrail, EventBridge, and SNS.

Log IAM changes with CloudTrail

Before we dive into implementation, let’s briefly understand the function of AWS CloudTrail. It records and logs activity within your AWS environment, tracking actions such as IAM role creation, deletion, or modification, thereby offering an audit trail of changes.

With this in mind, we’ll discuss the first step in tracking IAM changes: establishing a log for each modification. In this section, we’ll guide you through using CloudTrail to create these pivotal logs.

For an in-depth understanding of CloudTrail, refer to the AWS CloudTrail User Guide.

In this post, you’re going to start by creating a CloudTrail trail with the Management events type selected, and read and write API activity selected. If you already have a CloudTrail trail set up with those attributes, you can use that CloudTrail trail instead.

To create a CloudTrail log

  1. Open the AWS Management Console and select CloudTrail, and then choose Dashboard.
  2. In the CloudTrail dashboard, choose Create Trail.
    Figure 2: Use the CloudTrail dashboard to create a trail

    Figure 2: Use the CloudTrail dashboard to create a trail

  3. In the Trail name field, enter a display name for your trail and then select Create a new S3 bucket. Leave the default settings for the remaining trail attributes.
    Figure 3: Set the trail name and storage location

    Figure 3: Set the trail name and storage location

  4. Under Event type, select Management events. Under API activity, select Read and Write.
  5. Choose Next.
    Figure 4: Choose which events to log

    Figure 4: Choose which events to log

Set up notifications with Amazon SNS

Amazon SNS is a managed service that provides message delivery from publishers to subscribers. It works by allowing publishers to communicate asynchronously with subscribers by sending messages to a topic, a logical access point, and a communication channel. Subscribers can receive these messages using supported endpoint types, including email, which you will use in the blog example today.

For further reading on Amazon SNS, refer to the Amazon SNS Developer Guide.

Now that you’ve set up CloudTrail to log IAM changes, the next step is to establish a mechanism to notify you about these changes in real time.

To set up notifications

  1. Open the Amazon SNS console and choose Topics.
  2. Create a new topic. Under Type, select Standard and enter a name for your topic. Keep the defaults for the rest of the options, and then choose Create topic.
    Figure 5: Select Standard as the topic type

    Figure 5: Select Standard as the topic type

  3. Navigate to your topic in the topic dashboard, choose the Subscriptions tab, and then choose Create subscription.
    Figure 6: Choose Create subscription

    Figure 6: Choose Create subscription

  4. For Topic ARN, select the topic you created previously, then under Protocol, select Email and enter the email address you want the alerts to be sent to.
    Figure 7: Select the topic ARN and add an endpoint to send notifications to

    Figure 7: Select the topic ARN and add an endpoint to send notifications to

  5. After your subscription is created, go to the mailbox you designated to receive notifications and check for a verification email from the service. Open the email and select Confirm subscription to verify the email address and complete setup.

Initiate events with EventBridge

Amazon EventBridge is a serverless service that uses events to connect application components. EventBridge receives an event (an indicator of a change in environment) and applies a rule to route the event to a target. Rules match events to targets based on either the structure of the event, called an event pattern, or on a schedule.

Events that come to EventBridge are associated with an event bus. Rules are tied to a single event bus, so they can only be applied to events on that event bus. Your account has a default event bus that receives events from AWS services, and you can create custom event buses to send or receive events from a different account or AWS Region.

For a more comprehensive understanding of EventBridge, refer to the Amazon EventBridge User Guide.

In this part of our post, you’ll use EventBridge to devise a rule for initiating SNS notifications based on IAM configuration changes.

To create an EventBridge rule

  1. Go to the EventBridge console and select EventBridge Rule, and then choose Create rule.
    Figure 8: Use the EventBridge console to create a rule

    Figure 8: Use the EventBridge console to create a rule

  2. Enter a name for your rule, keep the defaults for the rest of rule details, and then choose Next.
    Figure 9: Rule detail screen

    Figure 9: Rule detail screen

  3. Under Target 1, select AWS service.
  4. In the dropdown list for Select a target, select SNS topic, select the topic you created previously, and then choose Next.
    Figure 10: Target with target type of AWS service and target topic of SNS topic selected

    Figure 10: Target with target type of AWS service and target topic of SNS topic selected

  5. Under Event source, select AWS events or EventBridge partner events.
    Figure 11: Event pattern with AWS events or EventBridge partner events selected

    Figure 11: Event pattern with AWS events or EventBridge partner events selected

  6. Under Event pattern, verify that you have the following selected.
    1. For Event source, select AWS services.
    2. For AWS service, select IAM.
    3. For Event type, select AWS API Call via CloudTrail.
    4. Select the radio button for Any operation.
    Figure 12: Event pattern details selected

    Figure 12: Event pattern details selected

Now that you’ve set up EventBridge to monitor IAM changes, test it by creating a new user or adding a new policy to an IAM role and see if you receive an email notification.

Centralize EventBridge alerts by using cross-account alerts

If you have multiple accounts, you should be evaluating using AWS Organizations. (For a deep dive into best practices for using AWS Organizations, we recommend reading this AWS blog post.)

By standardizing the implementation to channel alerts from across accounts to a primary AWS notification account, you can use a multi-account EventBridge architecture. This allows aggregation of notifications across your accounts through sender and receiver accounts. Figure 13 shows how this works. Separate member accounts within an AWS organizational unit (OU) have the same mechanism for monitoring changes and sending notifications as discussed earlier, but send notifications through an EventBridge instance in another account.

Figure 13: Multi-account EventBridge architecture aggregating notifications between two AWS member accounts to a primary management account

Figure 13: Multi-account EventBridge architecture aggregating notifications between two AWS member accounts to a primary management account

You can read more and see the implementation and deep dive of the multi-account EventBridge solution on the AWS samples GitHub, and you can also read more about sending and receiving Amazon EventBridge notifications between accounts.

Monitor calls to IAM

In this blog post example, you monitor calls to IAM.

The filter pattern you selected while setting up EventBridge matches CloudTrail events for calls to the IAM service. Calls to IAM have a CloudTrail eventSource of iam.amazonaws.com, so IAM API calls will match this pattern. You will find this simple default filter pattern useful if you have minimal IAM activity in your account or to test this example. However, as your account activity grows, you’ll likely receive more notifications than you need. This is when filtering only the relevant events becomes essential to prioritize your responses. Effectively managing your filter preferences allows you to focus on events of significance and maintain control as your AWS environment grows.

Monitor changes to IAM

If you’re interested only in changes to your IAM account, you can modify the event pattern inside EventBridge, the one you used to set up IAM notifications, with an eventName filter pattern, shown following.

"eventName": [
      "Add*",
      "Attach*",
      "Change*",
      "Create*",
      "Deactivate*",
      "Delete*",
      "Detach*",
      "Enable*",
      "Put*",
      "Remove*",
      "Set*",
      "Update*",
      "Upload*"
    ]

This filter pattern will only match events from the IAM service that begin with Add, Change, Create, Deactivate, Delete, Enable, Put, Remove, Update, or Upload. For more information about APIs matching these patterns, see the IAM API Reference.

To edit the filter pattern to monitor only changes to IAM

  1. Open the EventBridge console, navigate to the Event pattern, and choose Edit pattern.
    Figure 14: Modifying the event pattern

    Figure 14: Modifying the event pattern

  2. Add the eventName filter pattern from above to your event pattern.
    Figure 15: Use the JSON editor to add the eventName filter pattern

    Figure 15: Use the JSON editor to add the eventName filter pattern

Monitor changes to authentication and authorization configuration

Monitoring changes to authentication (security credentials) and authorization (policy) configurations is critical, because it can alert you to potential security vulnerabilities or breaches. For instance, unauthorized changes to security credentials or policies could indicate malicious activity, such as an attempt to gain unauthorized access to your AWS resources. If you’re only interested in these types of changes, use the preceding steps to implement the following filter pattern.

    "eventName": [
      "Put*Policy",
      "Attach*",
      "Detach*",
      "Create*",
      "Update*",
      "Upload*",
      "Delete*",
      "Remove*",
      "Set*"
    ]

This filter pattern matches calls to IAM that modify policy or create, update, upload, and delete IAM elements.

Conclusion

Monitoring IAM security configuration changes allows you another layer of defense against the unexpected. Balancing productivity and security, you might grant a user broad permissions in order to facilitate their work, such as exploring new AWS services. Although preventive measures are crucial, they can potentially restrict necessary actions. For example, a developer may need to modify an IAM role for their task, an alteration that could pose a security risk. This change, while essential for their work, may be undesirable from a security standpoint. Thus, it’s critical to have monitoring systems alongside preventive measures, allowing necessary actions while maintaining security.

Create an event rule for IAM events that are important to you and have a response plan ready. You can refer to Security best practices in IAM for further reading on this topic.

If you have questions or feedback about this or any other IAM topic, please visit the IAM re:Post forum. You can also read about the multi-account EventBridge solution on the AWS samples GitHub and learn more about sending and receiving Amazon EventBridge notifications between accounts.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Dylan Souvage

Dylan Souvage

Dylan is a Solutions Architect based in Toronto, Canada. Dylan loves working with customers to understand their business and enable them in their cloud journey. In his spare time, he enjoys martial arts, sports, anime, and traveling to warm, sunny places to spend time with his friends and family.

Abhra Sinha

Abhra Sinha

Abhra is a Toronto-based Enterprise Solutions Architect at AWS. Abhra enjoys being a trusted advisor to customers, working closely with them to solve their technical challenges and help build a secure, scalable architecture on AWS. In his spare time, he enjoys Photography and exploring new restaurants.

Adding approval notifications to EC2 Image Builder before sharing AMIs

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/adding-approval-notifications-to-ec2-image-builder-before-sharing-amis-2/

­­­­­This blog post is written by, Glenn Chia Jin Wee, Associate Cloud Architect, and Randall Han, Professional Services.

You may be required to manually validate the Amazon Machine Image (AMI) built from an Amazon Elastic Compute Cloud (Amazon EC2) Image Builder pipeline before sharing this AMI to other AWS accounts or to an AWS organization. Currently, Image Builder provides an end-to-end pipeline that automatically shares AMIs after they’ve been built.

In this post, we will walk through the steps to enable approval notifications before AMIs are shared with other AWS accounts. Image Builder supports automated image testing using test components. The recommended best practice is to automate test steps, however situations can arise where test steps become either challenging to automate or internal compliance policies mandate manual checks be conducted prior to distributing images. In such situations, having a manual approval step is useful if you would like to verify the AMI configuration before it is shared to other AWS accounts or an AWS Organization. A manual approval step reduces the potential for sharing an incorrectly configured AMI with other teams which can lead to downstream issues. This solution sends an email with a link to approve or reject the AMI. Users approve the AMI after they’ve verified that it is built according to specifications. Upon approving the AMI, the solution automatically shares it with the specified AWS accounts.

OverviewArchitecture Diagram

  1. In this solution, an Image Builder Pipeline is run that builds a Golden AMI in Account A. After the AMI is built, Image Builder publishes data about the AMI to an Amazon Simple Notification Service (Amazon SNS)
  2. The SNS Topic passes the data to an AWS Lambda function that subscribes to it.
  3. The Lambda function that subscribes to this topic retrieves the data, formats it, and then starts an SSM Automation, passing it the AMI Name and ID.
  4. The first step of the SSM Automation is a manual approval step. The SSM Automation first publishes to an SNS Topic that has an email subscription with the Approver’s email. The approver will receive the email with a URL that they can click to approve the step.
  5. The approval step defines a specific AWS Identity and Access Management (IAM) Role as an approver. This role has the minimum required permissions to approve the manual approval step. After performing manual tests on the Golden AMI, the Approver principal will assume this role.
  6. After assuming this role, the approver will click on the approval link that was sent via email. After approving the step, an AWS Lambda Function is triggered.
  7. This Lambda Function shares the Golden AMI with Account B and sends an email notifying the Target Account Recipients that the AMI has been shared.

Prerequisites

For this walkthrough, you will need the following:

  • Two AWS accounts – one to host the solution resources, and the second which receives the shared Golden AMI.
    • In the account that hosts the solution, prepare an AWS Identity and Access Management (IAM) principal with the sts:AssumeRole permission. This principal must assume the IAM Role that is listed as an approver in the Systems Manager approval step. The ARN of this IAM principal is used in the AWS CloudFormation Approver parameter, This ARN is added to the trust policy of approval IAM Role.
    • In addition, in the account hosting the solution, ensure that the IAM principal deploying the CloudFormation template has the required permissions to create the resources in the stack.
  • A new Amazon Virtual Private Cloud (Amazon VPC) will be created from the stack. Make sure that you have fewer than five VPCs in the selected Region.

Walkthrough

In this section, we will guide you through the steps required to deploy the Image Builder solution. The solution is deployed with CloudFormation.

In this scenario, we deploy the solution within the approver’s account. The approval email will be sent to a predefined email address for manual approval, before the newly created AMI is shared to target accounts.

The approver first assumes the approval IAM Role and then selects the approval link. This leads to the Systems Manager approval page. Upon approval, an email notification will be sent to the predefined target account email address, notifying the relevant stakeholders that the AMI has been successfully shared.

The high-level steps we will follow are:

  1. In Account A, deploy the provided AWS CloudFormation template. This includes an example Image Builder Pipeline, Amazon SNS topics, Lambda functions, and an SSM Automation Document.
  2. Approve the SNS subscription from your supplied email address.
  3. Run the pipeline from the Amazon EC2 Image Builder Console.
  4. [Optional] To conduct manual tests, launch an Amazon EC2 instance from the built AMI after the pipeline runs.
  5. An email will be sent to you with options to approve or reject the step. Ensure that you have assumed the IAM Role that is the approver before clicking the approval link that leads to the SSM console approval page.
  6. Upon approving the step, an AWS Lambda function shares the AMI to the Account B and also sends an email to the target account email recipients notifying them that the AMI has been shared.
  7. Log in to Account B and verify that the AMI has been shared.

Step 1: Deploy the AWS CloudFormation template

1. The CloudFormation template, template.yaml that deploys the solution can also found at this GitHub repository. Follow the instructions at the repository to deploy the stack.

Step 2: Verify your email address

  1. After running the deployment, you will receive an email prompting you to confirm the Subscription at the approver email address. Choose Confirm subscription.

SNS Topic Subscription confirmation email

  1. This leads to the following screen, which shows that your subscription is confirmed.

subscription-confirmation

  1. Repeat the previous 2 steps for the target email address.

Step 3: Run the pipeline from the Image Builder console

  1. In the Image Builder console, under Image pipelines, select the checkbox next to the Pipeline created, choose Actions, and select Run pipeline.

run-image-builder-pipeline

Note: The pipeline takes approximately 20 – 30 minutes to complete.

Step 4: [Optional] Launch an Amazon EC2 instance from the built AMI

If you have a requirement to manually validate the AMI before sharing it with other accounts or to the AWS organization an approver will launch an Amazon EC2 instance from the built AMI and conduct manual tests on the EC2 instance to make sure it is functional.

  1. In the Amazon EC2 console, under Images, choose AMIs. Validate that the AMI is created.

ami-in-account-a

  1. Follow AWS docs: Launching an EC2 instances from a custom AMI for steps on how to launch an Amazon EC2 instance from the AMI.

Step 5: Select the approval URL in the email sent

  1. When the pipeline is run successfully, you will receive another email with a URL to approve the AMI.

approval-email

  1. Before clicking on the Approve link, you must assume the IAM Role that is set as an approver for the Systems Manager step.
  2. In the CloudFormation console, choose the stack that was deployed.

cloudformation-stack

4. Choose Outputs and copy the IAM Role name.

ssm-approval-role-output

5. While logged in as the IAM Principal that has permissions to assume the approval IAM Role, follow the instructions at AWS IAM documentation for switching a role using the console to assume the approval role.
In the Switch Role page, in Role paste the name of the IAM Role that you copied in the previous step.

Note: This IAM Role was deployed with minimum permissions. Hence, seeing warning messages in the console is expected after assuming this role.

switch-role

6. Now in the approval email, select the Approve URL. This leads to the Systems Manager console. Choose Submit.

approve-console

7. After approving the manual step, the second step is executed, which shares the AMI to the target account.

automation-step-success

Step 6: Verify that the AMI is shared to Account B

  1. Log in to Account B.
  2. In the Amazon EC2 console, under Images, choose AMIs. Then, in the dropdown, choose Private images. Validate that the AMI is shared.

verify-ami-in-account-b

  1. Verify that a success email notification was sent to the target account email address provided.

target-email

Clean up

This section provides the necessary information for deleting various resources created as part of this post.

  1. Deregister the AMIs that were created and shared.
    1. Log in to Account A and follow the steps at AWS documentation: Deregister your Linux AMI.
  2. Delete the CloudFormation stack. For instructions, refer to Deleting a stack on the AWS CloudFormation console.

Conclusion

In this post, we explained how to enable approval notifications for an Image Builder pipeline before AMIs are shared to other accounts. This solution can be extended to share to more than one AWS account or even to an AWS organization. With this solution, you will be notified when new golden images are created, allowing you to verify the accuracy of their configuration before sharing them to for wider use. This reduces the possibility of sharing AMIs with misconfigurations that the written tests may not have identified.

We invite you to experiment with different AMIs created using Image Builder, and with different Image Builder components. Check out this GitHub repository for various examples that use Image Builder. Also check out this blog on Image builder integrations with EC2 Auto Scaling Instance Refresh. Let us know your questions and findings in the comments, and have fun!

Sign Amazon SNS messages with SHA256 hashing for HTTP subscriptions

Post Syndicated from Daniel Caminhas original https://aws.amazon.com/blogs/security/sign-amazon-sns-messages-with-sha256-hashing-for-http-subscriptions/

Amazon Simple Notification Service (Amazon SNS) now supports message signatures based on Secure Hash Algorithm 256 (SHA256) hashing. Amazon SNS signs the messages that are delivered from your Amazon SNS topic so that subscribed HTTP endpoints can verify the authenticity of the messages. In this blog post, we will show you how to enable message signatures based on SHA256 for your Amazon SNS topics.

About message signing verification

To verify the authenticity of a message sent to your HTTP endpoint by Amazon SNS, you can verify the message signature. There are two cases where we recommend verifying the authenticity of the message. The first is when Amazon SNS sends a message to an HTTP endpoint that you subscribed to a topic. The second is when Amazon SNS sends a confirmation message to your HTTP endpoint after the Subscribe or the Unsubscribe API actions. For more information, see Verifying the signatures of Amazon SNS messages in the Amazon SNS Developer Guide.

Amazon SNS now supports two message signature versions:

  • Signature version 1 – Amazon SNS creates the signature based on the SHA1 hash of the message.
  • Signature version 2 – Amazon SNS creates the signature based on the SHA256 hash of the message.

Amazon SNS adds the SignatureVersion property to the JSON payload of messages delivered to HTTP endpoints, as shown in the following code snippet. For more information on the JSON payload format, see Parsing message formats in the Amazon SNS Developer Guide.

{
  "Type" : "Notification",
  "MessageId" : "22b80b92-fdea-4c2c-8f9d-bdfb0c7bf324",
  "TopicArn" : "arn:aws:sns:us-west-2:123456789012:MyTopic",
  "Subject" : "My First Message",
  "Message" : "Hello world!",
  "Timestamp" : "2022-08-02T00:54:06.655Z",
  "SignatureVersion" : "2",
  "Signature" : "EXAMPLEw6JRN...",
  "SigningCertURL" : "https://sns.us-west-2.amazonaws.com/SimpleNotificationService-f3ecfb7224c7233fe7bb5f59f96de52f.pem",
  "UnsubscribeURL" : "https://sns.us-west-2.amazonaws.com/?Action=Unsubscribe&SubscriptionArn=arn:aws:sns:us-west-2:123456789012:MyTopic:c9135db0-26c4-47ec-8998-413945fb5a96"
}

What to consider before you enable message signatures based on SHA256 for your Amazon SNS topic

As an Amazon SNS topic owner, before you enable SHA256 support for your topic, we recommend communicating with the owners of the HTTP endpoints that are subscribed to your topic. They might need to update their message signature verification logic to accommodate the new signature version. If the endpoint owners are using the AWS SDK feature for verifying the Amazon SNS message signatures, they need to make sure that they are using one of the following versions of the AWS SDK: Java 1.12.285, JavaScript 0.3.5, Ruby 1.54.0, PHP 1.8.0 or .NET 3.7.3.96.

How to enable message signatures based on SHA256 for your Amazon SNS topic

By default, Amazon SNS topics use SHA1 for hashing the message signature. You can enable SHA256 support for your topic by setting the topic attribute SignatureVersion to 2 using the AWS Software Development Kit (AWS SDK), or AWS Command Line Interface (AWS CLI).

The following code example shows how to set the topic attribute SignatureVersion by using the AWS CLI.

aws sns set-topic-attributes \
    --topic-arn arn:aws:sns:us-west-2:123456789012:MyTopic \
    --attribute-name SignatureVersion \
    --attribute-value 2

The following code example shows how to set the SignatureVersion attribute by using the AWS SDK for Java.

public static void enableSHA256Support(SnsClient snsClient, String topicArn) {

        try {

            SetTopicAttributesRequest request = SetTopicAttributesRequest.builder()
                .attributeName("SignatureVersion")
                .attributeValue("2")
                .topicArn(topicArn)
                .build();

            SetTopicAttributesResponse result = snsClient.setTopicAttributes(request);
            System.out.println("\n\nStatus was " + result.sdkHttpResponse().statusCode() + "\n\nTopic " + request.topicArn()
                + " updated " + request.attributeName() + " to " + request.attributeValue());

        } catch (SnsException e) {
            System.err.println(e.awsErrorDetails().errorMessage());
        }
    }

Conclusion

Amazon SNS topic owners can now enable message signatures based on SHA256 hashing. In this post, you learned how to choose the hashing algorithm, either SHA256 or SHA1, for your SNS topic. For more information, see Verifying the signatures of Amazon SNS messages in the Amazon SNS Developer Guide, and SetTopicAttributes in the Amazon SNS API Reference.

For more serverless learning resources, visit Serverless Land.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Daniel Caminhas

Daniel is a software development engineer for Amazon SNS.

Author

Ahmed Abouzeid

Ahmed is a software development manager for Amazon SNS.

Build Health Aware CI/CD Pipelines

Post Syndicated from sangusah original https://aws.amazon.com/blogs/devops/build-health-aware-ci-cd-pipelines/

Everything fails all the time — Werner Vogels, AWS CTO

At the moment of imminent failure, you want to avoid an unlucky deployment. I’ll start here with a short story that demonstrates the purpose of this post.

The DevOps team has just started a database upgrade with a planned outage of 30 minutes. The team automated the entire upgrade flow, triggered a CI/CD pipeline with no human intervention, and the upgrade is progressing smoothly. Then, 20 minutes in, the pipeline is stuck, and your upgrade isn’t progressing. The maintenance window has expired and customers can’t transact. You’ve created a support case, and the AWS engineer confirmed that the upgrade is failing because of a running AWS Health incident in the us-west-2 Region. The engineer has directed the DevOps team to continue monitoring the status.aws.amazon.com page for updates regarding incident resolution. The event continued running for three hours, during which time customers couldn’t transact. Once resolved, the DevOps team retried the failed pipeline, and it completed successfully.

After the incident, the DevOps team explored the possibilities for avoiding these types of incidents in the future. The team was made aware of AWS Health API that provides programmatic access to AWS Health information. In this post, we’ll help the DevOps team make the most of the AWS Health API to proactively prevent unintended outages.

AWS provides Business and Enterprise Support customers with access to the AWS Health API. Customers can have access to running events in the AWS infrastructure that may impact their service usage. Incidents could be Regional, AZ-specific, or even account specific. During these incidents, it isn’t recommended to deploy or change services that are impacted by the event.

In this post, I will walk you through how to embed AWS Health API insights into your CI/CD pipelines to automatically stop deployments whenever an AWS Health event is reported in a Region that you’re operating in. Furthermore, I will demonstrate how you can automate detection and remediation.

The Demo

In this demo, I will use AWS CodePipeline to demonstrate the idea. I will build a simple pipeline that demonstrates the concept without going into the build, test, and deployment specifics.

CodePipeline Flow

The CodePipeline flow consists of three steps:

  1. Source stage that downloads a CloudFormation template from AWS CodeCommit. The template will be deployed in the last stage.
  2. Custom stage that invokes the AWS Lambda function to evaluate the AWS Health. The Lambda function calls the AWS Health API, evaluates the health risk, and calls back CodePipeline with the assessment result.
  3. Deploy stage that deploys the CloudFormation templates downloaded from CodeCommit in the first stage.
The CodePipeline flow consists of 3 steps. First, "source stage" that downloads a CloudFormation template from CodeCommit. The template will be deployed in the last stage. Step 2 is a "custom stage" that invokes the Lambda function to evaluate AWS Health. The Lambda function calls the AWS Health API, evaluates the health risk and calls back CodePipeline with the assessment result. Finally, step 3 is a "deploy stage" that deploys the CloudFormation template downloaded from CodeCommit in the first stage. If a health is detected in step 2, the workflow will retry after a predefined timeout.

Figure 1. CodePipeline workflow.

Lambda evaluation logic

The Lambda function evaluates whether or not a running AWS Health event may be impacted by the deployment. In this case, the following criteria must be met to consider it as safe to deploy:

  • Deployment will take place in the North Virginia Region and accordingly the Lambda function will filter on the us-east-1 Region.
  • A closed event is irrelevant. The Lambda function will filter events with only the open status.
  • AWS Health API can return different event types that may not be relevant, such as: Scheduled Maintenance, and Account and Billing notifications. The Lambda function will filter only “Issue” type events.

The AWS Health API follows a multi-Region application architecture and has two regional endpoints in an active-passive configuration. To support active-passive DNS failover, AWS Health provides a global endpoint. The Python code is available on GitHub with more information in the README on how to build the Lambda code package.

The Lambda function requires the following AWS Identity and Access Management (IAM) permissions to access AWS Health API, CodePipeline, and publish logs to CloudWatch:

{
  "Version": "2012-10-17", 
  "Statement": [
    {
      "Action": [ 
        "logs:CreateLogStream",
        "logs:CreateLogGroup",
        "logs:PutLogEvents"
      ],
      "Effect": "Allow", 
      "Resource": "arn:aws:logs:us-east-1:replaceWithAccountNumber:*"
    },
    {
      "Action": [
        "codepipeline:PutJobSuccessResult",
        "codepipeline:PutJobFailureResult"
        ],
        "Effect": "Allow",
        "Resource": "*"
     },
     {
        "Effect": "Allow",
        "Action": "health:DescribeEvents",
        "Resource": "*"
    }
  ]
}

Solution architecture

This is the solution architecture diagram. It involved three entities: AWS Code Pipeline, AWS Lambda and the AWS Health API. First, AWS Code Pipeline invoke the Lambda function asynchronously. Second, the Lambda function call the AWS Health API, DescribeEvents. Third, the DescribeEvents API will respond back with a list of health events. Finally, the Lambda function will respond with either a success response or a failed one through calling PutJobSuccessResult and PutJobFailureResults consecutively.

Figure 2. Solution architecture diagram.

In CodePipeline, create a new stage with a single action to asynchronously invoke a Lambda function. The function will call AWS Health DescribeEvents API to retrieve the list of active health incidents. Then, the function will complete the event analysis and decide whether or not it may impact the running deployment. Finally, the function will call back CodePipeline with the evaluation results through either PutJobSuccessResult or PutJobFailureResult API operations.

If the Lambda evaluation succeeds, then it will call back the pipeline with a PutJobSuccessResult API. In turn, the pipeline will mark the step as successful and complete the execution.

AWS Code Pipeline workflow execution snapshot from the AWS Console. The first step, Source is a success after completing source code download from AWS CodeCommit service. The second step, check the AWS service health is a success as well.

Figure 3. AWS Code Pipeline workflow successful execution.

If the Lambda evaluation fails, then it will call back the pipeline with a PutJobFailureResult API specifying a failure message. Once the DevOps team is made aware that the event has been resolved, select the Retry button to re-evaluate the health status.

AWS CodePipeline workflow execution snapshot from the AWS Console. The first step, Source is a success after completing source code download from AWS CodeCommit service. The second step, check the AWS service health has failed after detecting a running health event/incident in the operating AWS region.

Figure 4. AWS CodePipeline workflow failed execution.

Your DevOps team must be aware of failed deployments. Therefore, it’s a good idea to configure alerts to notify concerned stakeholders with failed stage executions. Create a notification rule that posts a Slack message if a stage fails. For detailed steps, see Create a notification rule – AWS CodePipeline. In case of failure, a Slack notification will be sent through AWS Chatbot.

A Slack UI snapshot showing the notification to be sent if a deployment fails to execute. The notification shows a title of "AWS CodePipeline Notification". The notification indicates that one action has failed in the stage aws-health-check. The notification also shows that the failure reason is that there is an Incident In Progress. The notification also mentions the Pipeline name as well as the failed stage name.

Figure 5. Slack UI snapshot notification for a failed deployment.

A more elegant solution involves pushing the notification to an SNS topic that in turns calls a Lambda function to retry the failed stage. The Lambda function extracts the pipeline failed stage identifier, and then calls the RetryStageExecution CodePipeline API.

Conclusion

We’ve learned how to create an automation that evaluates the risk associated with proceeding with a deployment in conjunction with a running AWS Health event. Then, the automation decides whether to proceed with the deployment or block the progress to avoid unintended downtime. Accordingly, this results in the improved availability of your application.

This solution isn’t exclusive to CodePipeline. However, the pattern can be applied to other CI/CD tools that your DevOps team uses.

Author:

Islam Ghanim

Islam Ghanim is a Senior Technical Account Manager at Amazon Web Services in Melbourne, Australia. He enjoys helping customers build resilient and cost-efficient architectures. Outside work, he plays squash, tennis and almost any other racket sport.

Adding approval notifications to EC2 Image Builder before sharing AMIs

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/adding-approval-notifications-to-ec2-image-builder-before-sharing-amis/

This blog post was written by, Glenn Chia Jin Wee, Associate Cloud Architect at AWS and Randall Han, Associate Professional Services Consultant at AWS.

In some situations, you may be required to manually validate the Amazon Machine Image (AMI) built from an Amazon Elastic Compute Cloud (Amazon EC2) Image Builder pipeline before sharing this AMI to other AWS accounts or to an AWS Organization. Currently, Image Builder provides an end-to-end pipeline that automatically shares AMIs after they’ve been built.

In this post, we will walk through the steps to enable approval notifications before AMIs are shared with other AWS accounts. Having a manual approval step could be useful if you would like to verify the AMI configurations before it is shared to other AWS accounts or an AWS Organization. This reduces the possibility of incorrectly configured AMIs being shared to other teams which in turn could lead to downstream issues if applications are installed using this AMI. This solution uses serverless resources to send an email with a link that automatically shares the AMI with the specified AWS accounts. Users select this link after they’ve verified that the AMI is built according to specifications.

Overview

Architecture Diagram

  1. In this solution, an Image Builder Pipeline is run that builds a Golden AMI in Account A. After the AMI is built, Image Builder publishes data about the AMI to an Amazon Simple Notification Service (Amazon SNS) topic.
  2. This SNS Topic passes the data to an AWS Lambda function that subscribes to it.
  3. The Lambda function that subscribes to this topic retrieves the data, formats it, and sends a customized email to another SNS Topic.
  4. The second SNS Topic has an email subscription with the Approver’s email. The approver will receive the customized email with a URL that interacts with the next set of Serverless resources.
  5. Selecting the URL makes a GET request to Amazon API Gateway, thereby passing the AMI ID in the query string.
  6. API Gateway then triggers another Lambda function and passes the AMI ID to it.
  7. The Lambda function obtains the AMI ID from the query string parameter of the API Gateway request, and then shares it with the provided target account.

Prerequisites

For this walkthrough, you will need the following:

Walkthrough

In this section, we will guide you through the steps required to deploy the Image Builder solution that utilizes Serverless resources. The solution is deployed with AWS SAM.

In this scenario, we deploy the solution within the approver’s account. The approval email will be sent to a predefined email address for manual approval, before the newly created AMI is shared to target accounts.

Once the approver selects the approval link, an email notification will be sent to the predefined target account email address, notifying that the AMI has been successfully shared.

The high-level steps we will follow are:

  1. In Account A, deploy the provided AWS SAM template. This includes an example Image Builder Pipeline, Amazon SNS topics, API Gateway, and Lambda functions.
  2. Approve the SNS subscription from your supplied email address.
  3. Run the pipeline from the Amazon EC2 Image Builder Console.
  4. [Optional] After the pipeline runs, launch an Amazon EC2 instance from the built AMI to conduct manual tests
  5. An Amazon SNS email will be sent to you with an API Gateway URL. When clicked, an AWS Lambda function shares the AMI to the Account B.
  6. Log in to Account B and verify that the AMI has been shared.

Step 1: Launch the AWS SAM template

  1. Clone the SAM templates from this GitHub repository.
  2. Run the following command to deploy the templates via SAM. Replace <approver email> with the Approver’s email and <AWS Account B ID> with the AWS Account ID of your second AWS Account.

sam deploy \

–template-file template.yaml \

–stack-name ec2-image-builder-approver-notifications \

–capabilities CAPABILITY_IAM \

–resolve-s3 \

–parameter-overrides \

ApproverEmail=<approver email> \

TargetAccountEmail=<target account email> \

TargetAccountlds=<AWS Account B ID>

Step 2: Verify your email address

  1. After running the deployment, you will receive an email prompting you to confirm the Subscription at the approver email address. Choose Confirm subscription.

Email to confirm SNS topic subscription

  1. This leads to the following screen, which shows that your subscription is confirmed.

SNS topic subscription confirmation

  1. Repeat the previous 2 steps for the target email address.

Step 3: Run the pipeline from the Image Builder console

  1. In the Image Builder console, under Image pipelines, select the checkbox next to the Pipeline created, choose Actions, and select Run pipeline.

Run the Image Builder Pipeline

Note that the pipeline takes approximately 20 to 30 minutes to complete.

Step 4: [Optional] Launch an Amazon EC2 instance from the built AMI

There could be a requirement to manually validate the AMI before sharing it to other AWS accounts or to the AWS organization. With this requirement, approvers will launch an Amazon EC2 instance from the built AMI and conduct manual tests on the EC2 instance to make sure that it is functional.

  1. In the Amazon EC2 console, under Images, choose AMIs. Validate that the AMI is created.

Validate the AMI has been built

  1. Follow AWS docs: Launching an EC2 instances from a custom AMI for steps on how to launch an Amazon EC2 instance from the AMI.

Step 5: Select the approval URL in the email sent

  1. When the pipeline is run successfully, you will receive another email with a URL to share the AMI.

Approval link to share the AMI to Account B

2. Selecting this URL results in the following screen which shows that the AMI share is successful.

Result showing the AMI was successfully shared after selecting the approval link

Step 6: Verify that the AMI is shared to Account B

  1. Log in to Account B.
  2. In the Amazon EC2 console, under Images, choose AMIs. Then, in the dropdown, choose Private images. Validate that the AMI is shared.

AMI is shared when Private images are selected from the dropdown

3. Verify that a success email notification was sent to the target account email address provided.

Successful AMI share email notification sent to Target Account Email Address

Clean up

This section provides the necessary information for deleting various resources created as part of this post.

1. Deregister the AMIs created and shared.

a. Log in to Account A and follow the steps at AWS documentation: Deregister your Linux AMI.

2. Delete the SAM stack with the following command. Replace <region> with the Region of choice.

sam delete –stack-name ec2-image-builder-approver-notifications –no-prompts –region <region>

3. Delete the CloudWatch log groups for the Lambda functions. You’ll identify it with the name `/aws/lambda/ec2-image-builder-approve*`.

4. Consider deleting the Amazon S3 bucket used to store the packaged Lambda artifact.

Conclusion

In this post, we explained how to use Serverless resources to enable approval notifications for an Image Builder pipeline before AMIs are shared to other accounts. This solution can be extended to share to more than one AWS account or even to an AWS organization. With this solution, you will be notified when new golden images are created, allowing you to verify the correctness of their configuration before sharing them to for wider use. This reduces the possibility of sharing AMIs with misconfigurations that the written tests may not have identified.

We invite you to experiment with different AMIs created using Image Builder, and with different Image Builder components. Check out this GitHub repository for various examples that use Image Builder. Also check out this blog on Image builder integrations with EC2 Auto Scaling Instance Refresh. Let us know your questions and findings in the comments, and have fun!

Automatically update security groups for Amazon CloudFront IP ranges using AWS Lambda

Post Syndicated from Yeshwanth Kottu original https://aws.amazon.com/blogs/security/automatically-update-security-groups-for-amazon-cloudfront-ip-ranges-using-aws-lambda/

Amazon CloudFront is a content delivery network that can help you increase the performance of your web applications and significantly lower the latency of delivering content to your customers. For CloudFront to access an origin (the source of the content behind CloudFront), the origin has to be publicly available and reachable. Anyone with the origin domain name or IP address could request content directly and bypass CloudFront. In this blog post, I describe an automated solution that uses security groups to permit only CloudFront to access the origin.

Amazon Simple Storage Service (Amazon S3) origins provide a feature called Origin Access Identity, which blocks public access to selected buckets, making them accessible only through CloudFront. When you use CloudFront to secure your web applications, it’s important to ensure that only CloudFront can access your origin (such as Amazon Elastic Cloud Compute (Amazon EC2) or Application Load Balancer (ALB)) and any direct access to origin is restricted. This blog post shows you how to create an AWS Lambda function to automatically update Amazon Virtual Private Cloud (Amazon VPC) security groups with CloudFront service IP ranges to permit only CloudFront to access the origin.

AWS publishes the IP ranges in JSON format for CloudFront and other AWS services. If your origin is an Elastic Load Balancer or an Amazon EC2 instance, you can use VPC security groups to allow only CloudFront IP ranges to access your applications. The IP ranges in the list are separated by service and Region, and you must specify only the IP ranges that correspond to CloudFront.

The IP ranges that AWS publishes change frequently and without an automated solution, you would need to retrieve this document frequently to understand the current IP ranges for CloudFront. Frequent polling is inefficient because there is no notice of when the IP ranges change, and if these IP ranges aren’t modified immediately, your client might see 504 errors when they access CloudFront. Additionally, there are numerous IP ranges for each service, performing the change manually isn’t an efficient way of updating these ranges. This means you need infrastructure to support the task. However, in that case you end up with another host to manage—complete with the typical patching, deployment, and monitoring. As you can see, a small task could quickly become more complicated than the problem you intended to solve.

An Amazon Simple Notification Service (Amazon SNS) message is sent to a topic whenever the AWS IP ranges change. Enabling you to build an event-driven, serverless solution that updates the IP ranges for your security groups, as needed by using a Lambda function that is triggered in response to the SNS notification.

Here are the steps we are going to take to implement the solution:

  1. Create your resources
    1. Create an IAM policy and execution role for the Lambda function
    2. Create your Lambda function
  2. Test your Lambda function
  3. Configure your Lambda function’s trigger

Create your resources

The first thing you need to do is create a Lambda function execution role and policy. Lambda function uses execution role to access or create AWS resources. This Lambda function is triggered by an SNS notification whenever there’s a change in the IP ranges document. Based on the number of IP ranges present for CloudFront and also the number of ports (for example, 80,443) that you want to whitelist on the origin, this Lambda function creates the required security groups. These security groups will allow only traffic from CloudFront to your ELB load balancers or EC2 instances.

Create an IAM policy and execution role for the Lambda function

When you create a Lambda function, it’s important to understand and properly define the security context for the Lambda function. Using AWS Identity and Access Management (IAM), you can create the Lambda execution role that determines the AWS service calls that the function is authorized to complete. (Learn more about the Lambda permissions model.)

To create the IAM policy for your role

  1. Log in to the IAM console with the user account that you will use to manage the Lambda function. This account must have administrator permissions.
  2. In the navigation pane, choose Policies.
  3. In the content pane, choose Create policy.
  4. Choose the JSON tab and copy the text from the following JSON policy document. Paste this text into the JSON text box.
    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Sid": "CloudWatchPermissions",
          "Effect": "Allow",
          "Action": [
            "logs:CreateLogGroup",
            "logs:CreateLogStream",
            "logs:PutLogEvents"
          ],
          "Resource": "arn:aws:logs:*:*:*"
        },
        {
          "Sid": "EC2Permissions",
          "Effect": "Allow",
          "Action": [
            "ec2:DescribeSecurityGroups",
            "ec2:AuthorizeSecurityGroupIngress",
            "ec2:RevokeSecurityGroupIngress",
            "ec2:CreateSecurityGroup",
            "ec2:DescribeVpcs",
    		"ec2:CreateTags",
            "ec2:ModifyNetworkInterfaceAttribute",
            "ec2:DescribeNetworkInterfaces"
            
          ],
          "Resource": "*"
        }
      ]
    }
    

  5. When you’re finished, choose Review policy.
  6. On the Review page, enter a name for the policy name (e.g. LambdaExecRolePolicy-UpdateSecurityGroupsForCloudFront). Review the policy Summary to see the permissions granted by your policy, and then choose Create policy to save your work.

To understand what this policy allows, let’s look closely at both statements in the policy. The first statement allows the Lambda function to create and write to CloudWatch Logs, which is vital for debugging and monitoring our function. The second statement allows the function to get information about existing security groups, get existing VPC information, create security groups, and authorize and revoke ingress permissions. It’s an important best practice that your IAM policies be as granular as possible, to support the principal of least privilege.

Now that you’ve created your policy, you can create the Lambda execution role that will use the policy.

To create the Lambda execution role

  1. In the navigation pane of the IAM console, choose Roles, and then choose Create role.
  2. For Select type of trusted entity, choose AWS service.
  3. Choose the service that you want to allow to assume this role. In this case, choose Lambda.
  4. Choose Next: Permissions.
  5. Search for the policy name that you created earlier and select the check box next to the policy.
  6. Choose Next: Tags.
  7. (Optional) Add metadata to the role by attaching tags as key-value pairs. For more information about using tags in IAM, see Tagging IAM Users and Roles.
  8. Choose Next: Review.
  9. For Role name (e.g. LambdaExecRole-UpdateSecurityGroupsForCloudFront), enter a name for your role.
  10. (Optional) For Role description, enter a description for the new role.
  11. Review the role, and then choose Create role.

Create your Lambda function

Now, create your Lambda function and configure the role that you created earlier as the execution role for this function.

To create the Lambda function

  1. Go to the Lambda console in N. Virginia region and choose Create function. On the next page, choose Author from scratch. (I’ll be providing the code for your Lambda function, but for other functions, the Use a blueprint option can be a great way to get started.)
  2. Give your Lambda function a name (e.g UpdateSecurityGroupsForCloudFront) and description, and select Python 3.8 from the Runtime menu.
  3. Choose or create an execution role: Select the execution role you created earlier by selecting the option Use an Existing Role.
  4. After confirming that your settings are correct, choose Create function.
  5. Paste the Lambda function code from here.
  6. Select Save.

Additionally, in the Basic Settings of the Lambda function, increase the timeout to 10 seconds.

To set the timeout value in the Lambda console

  1. In the Lambda console, choose the function you just created.
  2. Under Basic settings, choose Edit.
  3. For Timeout, select 10s.
  4. Choose Save.

By default, the Lambda function has these settings:

  • The Lambda function is configured to create security groups in the default VPC.
  • CloudFront IP ranges are updated as inbound rules on port 80.
  • The created security groups are tagged with the name prefix AUTOUPDATE.
  • Debug logging is turned off.
  • The service for which IP ranges are extracted is set to CloudFront.
  • The SDK client in the Lambda function set to us-east-1(N. Virginia).

If you want to customize these settings, set the following environment variables for the Lambda function. For more details, see Using AWS Lambda environment variables.

Action Key-value data
To create security groups in a specific VPC Key: VPC_ID
Value: vpc-id
To create security groups rules for a different port or multiple ports
 
The solution in this example supports a total of two ports. One can be used for HTTP and another for HTTPS.

Key: PORTS
Value: portnumber
or
Key: PORTS
Value: portnumber,portnumber
To customize the prefix name tag of your security groups Key: PREFIX_NAME
Value: custom-name
To enable debug logging to CloudWatch Key: DEBUG
Value: true
To extract IP ranges for a different service other than CloudFront Key: SERVICE
Value: servicename
To configure the Region for the SDK client used in the Lambda function
 
If the CloudFront origin is present in a different Region than N. Virginia, the security groups must be created in that region.
Key: REGION
Value: regionname

To set environment variables in the Lambda console

  1. In the Lambda console, choose the function you created.
  2. Under Environment variables, choose Edit.
  3. Choose Add environment variable.
  4. Enter a key and value.
  5. Choose Save.

Test your Lambda function

Now that you’ve created your function, it’s time to test it and initialize your security group.

To create your test event for the Lambda function

  1. In the Lambda console, on the Functions page, choose your function. In the drop-down menu next to Actions, choose Configure test events.
  2. Enter an Event Name (e.g. TriggerSNS)
  3. Replace the following as your sample event, which will represent an SNS notification and then select Create.
    {
        "Records": [
            {
                "EventVersion": "1.0",
                "EventSubscriptionArn": "arn:aws:sns:EXAMPLE",
                "EventSource": "aws:sns",
                "Sns": {
                    "SignatureVersion": "1",
                    "Timestamp": "1970-01-01T00:00:00.000Z",
                    "Signature": "EXAMPLE",
                    "SigningCertUrl": "EXAMPLE",
                    "MessageId": "95df01b4-ee98-5cb9-9903-4c221d41eb5e",
                    "Message": "{\"create-time\": \"yyyy-mm-ddThh:mm:ss+00:00\", \"synctoken\": \"0123456789\", \"md5\": \"7fd59f5c7f5cf643036cbd4443ad3e4b\", \"url\": \"https://ip-ranges.amazonaws.com/ip-ranges.json\"}",
                    "Type": "Notification",
                    "UnsubscribeUrl": "EXAMPLE",
                    "TopicArn": "arn:aws:sns:EXAMPLE",
                    "Subject": "TestInvoke"
                }
      		}
        ]
    }
    

  4. After you’ve added the test event, select Save and then select Test. Your Lambda function is then invoked, and you should see log output at the bottom of the console in Execution Result section, similar to the following.
    Updating from https://ip-ranges.amazonaws.com/ip-ranges.json
    MD5 Mismatch: got 2e967e943cf98ae998efeec05d4f351c expected 7fd59f5c7f5cf643036cbd4443ad3e4b: Exception
    Traceback (most recent call last):
      File "/var/task/lambda_function.py", line 29, in lambda_handler
        ip_ranges = json.loads(get_ip_groups_json(message['url'], message['md5']))
      File "/var/task/lambda_function.py", line 50, in get_ip_groups_json
        raise Exception('MD5 Missmatch: got ' + hash + ' expected ' + expected_hash)
    Exception: MD5 Mismatch: got 2e967e943cf98ae998efeec05d4f351c expected 7fd59f5c7f5cf643036cbd4443ad3e4b
    

  5. Edit the sample event again, and this time change the md5 value in the sample event to be the first MD5 hash provided in the log output. In this example, you would update the md5 value in the sample event configured earlier with the hash value seen in the error ‘2e967e943cf98ae998efeec05d4f351c’. Lambda code successfully executes only when the original hash of the IP ranges document and the hash received from the event trigger match. After you modify the hash value from the error message received earlier, the test event matches the hash of the IP ranges document.
  6. Select Save and test. This invokes your Lambda function.

After the function is invoked the second time with updated md5 has Lambda function should execute without any errors. You should be able to see the new security groups created and the IP ranges of CloudFront updated in the rules in the EC2 console, as shown in Figure 1.
 

Figure 1: EC2 console showing the security groups created

Figure 1: EC2 console showing the security groups created

In the initial successful run of this function, it created the total number of security groups required to update all the IP ranges of CloudFront for the ports mentioned. The function creates security groups based on the maximum number of rules that can be added to individual security groups. The new security groups can be identified from the EC2 console by the name AUTOUPDATE_random if you used the default configuration, or a custom name if you provided a PREFIX_NAME.

You can now attach these security groups to your Elastic LoadBalancer or EC2 instances. If your log output is different from what is described here, the output should help you identify the issue.

Configure your Lambda function’s trigger

After you’ve validated that your function is executing properly, it’s time to connect it to the SNS topic for IP changes. To do this, use the AWS Command Line Interface (CLI). Enter the following command, making sure to replace Lambda ARN with the Amazon Resource Name (ARN) of your Lambda function. You can find this ARN at the top right when viewing the configuration of your Lambda function.

aws sns subscribe - -topic-arn "arn:aws:sns:us-east-1:806199016981:AmazonIpSpaceChanged" - -region us-east-1 - -protocol lambda - -notification-endpoint "Lambda ARN"

You should receive the ARN of your Lambda function’s SNS subscription.

Now add a permission that allows the Lambda function to be invoked by the SNS topic. The following command also adds the Lambda trigger.

aws lambda add-permission - -function-name "Lambda ARN" - -statement-id lambda-sns-trigger - -region us-east-1 - -action lambda:InvokeFunction - -principal sns.amazonaws.com - -source-arn "arn:aws:sns:us-east-1:806199016981:AmazonIpSpaceChanged"

When AWS changes any of the IP ranges in the document, an SNS notification is sent and your Lambda function will be triggered. This Lambda function verifies the modified ranges in the document and efficiently updates the IP ranges on the existing security groups. Additionally, the function dynamically scales and creates additional security groups if the number of IP ranges for CloudFront is increased in future. Any newly created security groups are automatically attached to the network interface where the previous security groups are attached in order to avoid service interruption.

Summary

As you followed this blog post, you created a Lambda function to create a security groups and update the security group’s rules dynamically whenever AWS publishes new internal service IP ranges. This solution has several advantages:

  • The solution isn’t designed as a periodic poll, so it only runs when it needs to.
  • It’s automatic, so you don’t need to update security groups manually which lowers the operational cost.
  • It’s simple, because you have no extra infrastructure to maintain as the solution is completely serverless.
  • It’s cost effective, because the Lambda function runs only when triggered by the AmazonIpSpaceChanged SNS topic and only runs for a few seconds, this solution costs only pennies to operate.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon CloudFront forum. If you have any other use cases for using Lambda functions to dynamically update security groups, or even other networking configurations such as VPC route tables or ACLs, we’d love to hear about them!

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Yeshwanth Kottu

Yeshwanth is a Systems Development Engineer at AWS in Cupertino, CA. With a focus on CloudFront and Lambda@Edge, he enjoys helping customers tackle challenges through cloud-scale architectures. Yeshwanth has an MS in Computer Systems Networking and Telecommunications from Northeastern University. Outside of work, he enjoys travelling, visiting national parks, and playing cricket.