Amazon Elastic Compute Cloud (Amazon EC2) accelerated computing instances run some of the most demanding workloads customers operate, from large model training and distributed fine-tuning to high-throughput, live inference. These customers seek high availability and performance to make sure their training and inference run efficiently. To meet their performance goals, customers require visibility into the efficiency and performance of each accelerated computing chip in their fleet.
For example, central infrastructure or machine learning teams often operate accelerated computing capacity for many application teams. These infrastructure teams need a clear view of utilization and health across every instance in their fleet even if they don’t develop the applications running on those instances. They are often responsible for how efficiently that capacity is used and for hardware health, while application teams own the workload. Customers asked us to provide foundational telemetry for their accelerated computing efficiency and status that doesn’t require setup within the instance and complements their in-guest tooling.
Amazon EC2 now reports one-minute graphics processing unit (GPU) metrics through Detailed Monitoring and surfaces recoverable conditions with performance status checks. One-minute GPU metrics in Amazon EC2 Detailed Monitoring report per-GPU utilization and thermal data to Amazon CloudWatch, so you can identify underused capacity and tune workloads for cost and throughput. Performance status checks report recoverable hardware conditions, such as a GPU memory error, to help you manage GPU performance.
Feature overviews
Amazon EC2 reports GPU metrics and performance status checks without an in-guest agent and without using instance compute. These capabilities are available on supported NVIDIA GPU-based accelerated computing instance types. For the metrics supported on each instance family, see the Amazon EC2 Detailed Monitoring documentation.
One-minute accelerated computing metrics extend EC2 Detailed Monitoring and are published to CloudWatch as OpenTelemetry Metrics or CloudWatch Metrics. The metric name you add to a category determines which one CloudWatch publishes: include GPUUtilization for a CloudWatch Metric, instance.gpu.utilization for an OpenTelemetry Metric, or both names to publish both. Amazon EC2 publishes each metric to CloudWatch at two levels: one series for the instance, identified by InstanceId, and one series for each GPU, identified by InstanceId and GpuId. GpuId is the GPU UUID, which you can match to a device by running nvidia-smi -L on the instance.
Performance status checks add a fifth status check to the existing Amazon EC2 product check suite of system, instance, attached EBS, and application status checks. The check reports recoverable hardware issues that affect accelerated computing performance while the instance might remain running and reachable. It surfaces through the EC2 console, through DescribeInstanceStatus, and in CloudWatch metrics.
Evaluating accelerated computing utilization and performance with EC2 Detailed Monitoring
Amazon EC2 Detailed Monitoring reports per-GPU measurements, including compute activity, memory use, temperature, and data movement.
GPU utilization metrics report different aspects of GPU use. GPUPowerUtilization is available by default and reports active power use. Power utilization scales with the depth of work the GPU performs. Compare it with more granular utilization metrics to see how efficiently your workload uses the GPUs. GPU utilization shows the percentage of time the GPU was running work. Because a busy GPU might use only a fraction of its streaming multiprocessors (SMs), compare it with SM utilization to see how much of the compute capacity the workload uses. Memory utilization shows how much of the GPU’s memory capacity is in use, helping you assess memory headroom. Context accumulated time is a running total of the time a process has held the GPU open, whether or not it ran work. Use the CloudWatch metric math expression RATE(m1)/1000000, where m1 is GPUContextAccumulatedTime, to compare context activity with GPU utilization. A result close to 1 with low GPU utilization indicates that a GPU context is held open but idle.
GPU temperature is reported as a percentage of the GPU’s thermal throttle limit, and memory temperature as a percentage of the memory’s critical temperature. Both metrics can report values above 100 percent when a GPU or its memory runs above the limit. A GPU reduces its clocks when it reaches its throttle limit, so a value at or above 100 percent can explain a drop in throughput. You can correlate these measurements with GPU and interconnect utilization metrics to understand workload performance.
Interconnect utilization metrics show how much of the available bandwidth a workload uses for data movement. Each value reports the busier direction, either send or receive. NVLink utilization measures GPU-to-GPU traffic, such as collective operations in distributed training. It reports all of the GPU’s links together. PCIe utilization measures traffic between the host and the GPU.
Getting started with EC2 Detailed Monitoring
Amazon EC2 Detailed Monitoring publishes instance metrics to Amazon CloudWatch at one-minute intervals without running an agent in the guest operating system. You can publish these as OpenTelemetry Metrics or CloudWatch Metrics.
To get started, create a metric category, an Amazon EC2 resource containing the metrics you want to collect. Next, associate the category with one or more instances. For an existing instance, provide the category ID when you enable Detailed Monitoring with the MonitorInstances API. For a new instance, provide the category ID in the Monitoring object when you call RunInstances or configure a launch template.
The following example creates a metric category for GPU utilization, SM utilization, and memory utilization.
Categories apply to many instances at once, unlike per-instance metric settings. Define the metric set once and associate it wherever it applies. Every associated instance then reports the same set of metrics. Changing a category updates the metric set for every associated instance. The change is eventually consistent across running instances. Add the category to a launch template to apply the same metrics to new instances. This gives you one metric definition per workload type instead of one configuration per host. Metrics apply under standard Amazon CloudWatch pricing.
Managing accelerated computing availability with performance status checks
Accelerated computing hardware can experience non-terminal issues that affect performance and can be resolved with a GPU reset or an instance reboot. For example, when a GPU encounters an uncorrectable memory error, it schedules a repair that remaps the affected row to a spare. The repair takes effect the next time the GPU is reset or the instance is rebooted.
Amazon EC2 performance status checks surface these recoverable hardware conditions. For example, when Amazon EC2 detects a pending GPU memory row remap, the instance’s performance status check reports an impaired status and identifies reboot as the recommended remediation.
You can view performance status checks on the Amazon EC2 console or through DescribeInstanceStatus. Amazon EC2 also publishes the StatusCheckFailed_Performance metric to CloudWatch. A failed performance status check also increments the combined StatusCheckFailed metric. The following example uses the EC2 DescribeInstanceStatus API:
The following response shows the system, instance, attached EBS, and configured application status checks passing while the performance status check is impaired:
Amazon EC2 sends a scheduled event for the instance if the condition requires further action after a reboot.
To act on these conditions across your accelerated computing instances, create a CloudWatch alarm on StatusCheckFailed_Performance.
The alarm on StatusCheckFailed_Performance fires for an instance in a training cluster.
You confirm the condition and the recommended action with DescribeInstanceStatus, which returns a status of impaired and a remediation of reboot.
You checkpoint the job if applicable, then drain the node and reboot the instance at a planned point. On Amazon Elastic Kubernetes Service (Amazon EKS), cordon and drain the node. In Slurm, set the node to DRAIN.
After the reboot completes, the performance status check returns to ok.
The following command creates that alarm for a single instance.
A CloudWatch Metrics Insights alarm evaluates a single query across all matching instances, so one alarm can cover a large fleet. To drive automation without an alarm, poll the DescribeInstanceStatus API.
Rebooting the instance is the recommended remediation. Alternatively, you can reset the affected GPU while keeping the other GPUs running. On the affected instance, run nvidia-smi -q -d ROW_REMAPPER and find the GPU that reports Pending: Yes. Stop all processes using that GPU, then use root permissions to run nvidia-smi -r -i <GPU_UUID>. The performance status check returns to ok shortly after the reset completes.
Bringing it all together
Accelerated computing metrics and performance status checks address complementary questions. Detailed Monitoring metrics help you find idle or underused capacity and tune workloads for cost and throughput. Performance status checks surface recoverable conditions and recommend remediation. Together, these EC2 signals report utilization and status across the capacity infrastructure teams manage, while in-guest tooling provides workload-specific analysis.
For example, a central infrastructure team monitors how efficiently workloads use the accelerated computing instances it manages for several application teams. It finds that one team’s GPUs report lower GPU utilization and power utilization than comparable workloads run by other teams. The infrastructure team shares the finding and relevant workload-tuning practices with the application team. After the application team updates that workload, the infrastructure team uses the same CloudWatch metrics to evaluate the change. The infrastructure team also monitors StatusCheckFailed_Performance across the fleet. When a check reports an impaired status and recommends a reboot, the orchestrator saves the active job, stops placing new work on the instance, and reboots it. After the check returns to ok, the orchestrator makes the instance available for new jobs. Together, these workflows help the team improve GPU utilization, protect job progress, and return affected capacity to service.
Amazon EC2 Detailed Monitoring reports accelerated computing metrics once per minute at the instance and GPU levels. Performance status checks report recoverable conditions at the instance level. Infrastructure teams can use these EC2 signals to monitor utilization and status across the capacity they manage. In-guest tools add process, container, Kubernetes pod, and sub-minute detail.
Amazon EC2 Detailed Monitoring reports metrics for your instances, including GPU utilization metrics reported per GPU. Performance status checks tell you when accelerated computing hardware needs attention. These capabilities help you evaluate utilization and manage the efficiency of your accelerated computing fleets. To learn more, see the Amazon EC2 Detailed Monitoring documentation and the EC2 status checks documentation.
Note (November 2026): This post covers both MCP servers because the Redshift MCP Server has Redshift-specific settings, such as read-only by default and a cap on result rows, that the AWS MCP Server doesn’t have yet. We’ll update this post when the AWS MCP Server reaches parity.
Guardrails and cost control matter more as AI agents handle an increasing share of the queries in your analytics environments. Asked “Why did revenue drop in the West region last weekend?”, an agent finds the tables, writes and runs the SQL on Amazon Redshift, and follows up. This is agentic analytics, on your data warehouse and lakehouse.
Excessive agency: The agent can do too much. An agent acts on what a model decides. With more tools or permissions than its task needs, a misread request or an instruction hidden in a support ticket can become a real action, such as exporting customer records.
Unbounded consumption: The agent can spend too much. A retry loop can rerun a heavy query all night. A query can return millions of rows that the agent then sends to the model as input tokens. Finally, one SQL query that runs Amazon Bedrock model inference through Redshift ML invokes the model once for every row it processes.
Redshift includes the controls for both at no additional charge: per-agent roles, row-level and column-level security, dynamic data masking, read-only tools, workload management, and usage limits. You pay for queries from agents as you do for queries from any other client: for the compute and storage they use (Amazon Redshift pricing). Your agent’s model provider bills its model tokens, for example at Amazon Bedrock pricing when the agent uses a model in Amazon Bedrock. You pay for the Amazon Bedrock, Amazon Bedrock AgentCore, and monitoring controls in this post at their own rates.
In this post, we show you how to add guardrails and cost controls to agentic analytics on Redshift, using one model: six guardrails, three enforcement layers, and one cost envelope.
The layered guardrail model
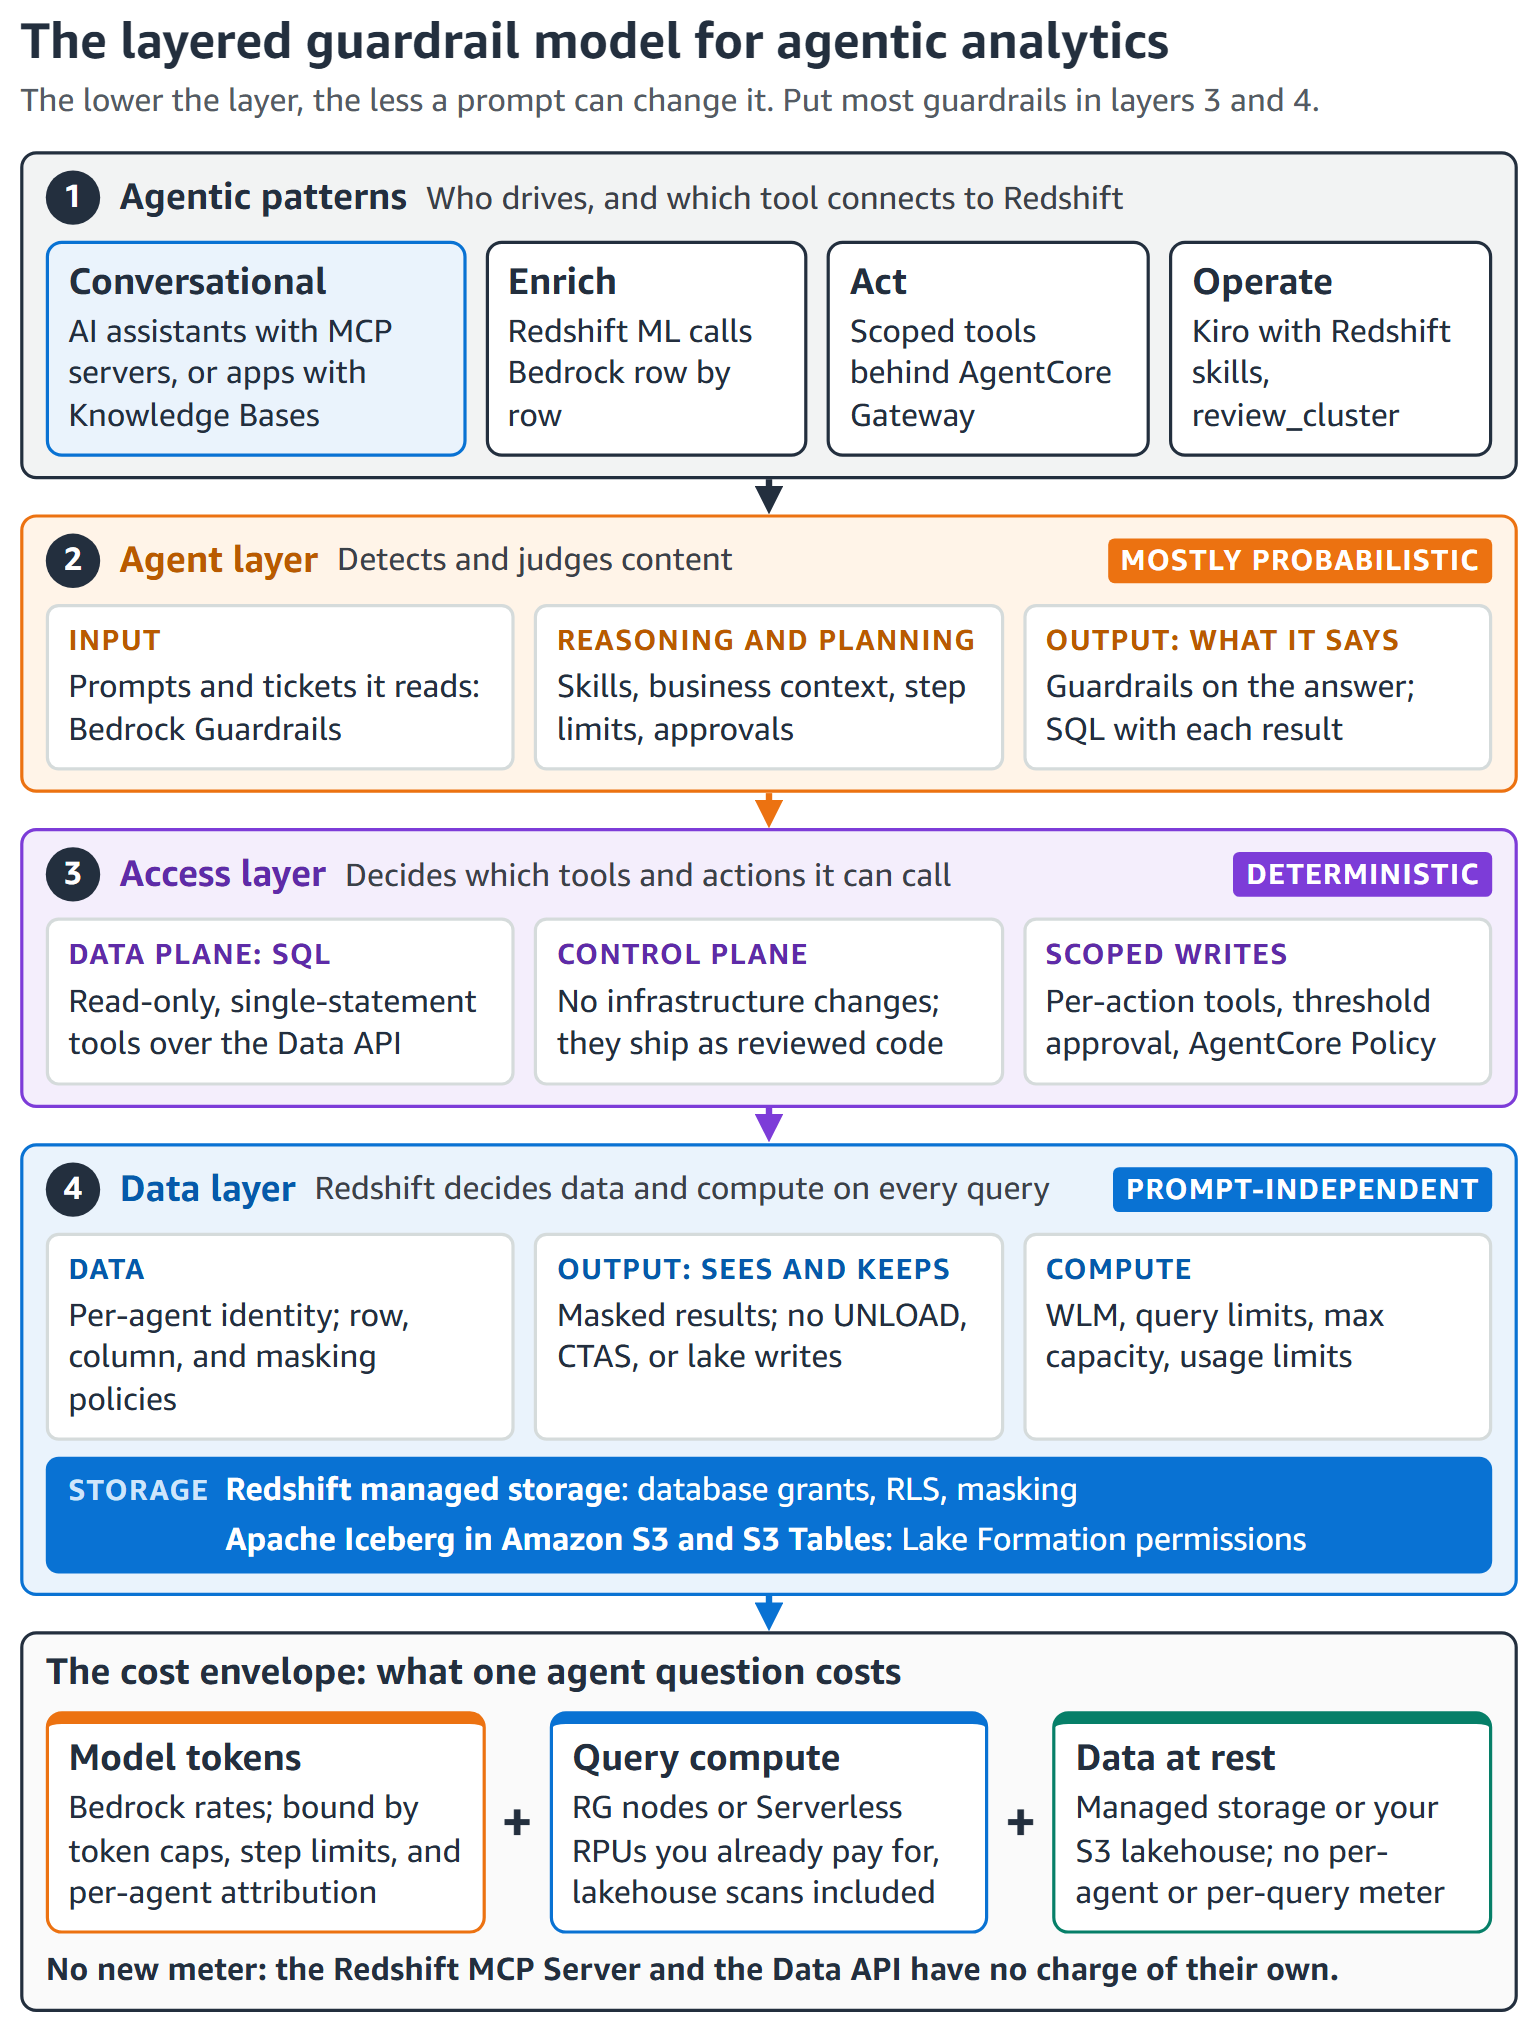
Each request passes through the agent layer, the access layer, and the data layer before it reaches your data warehouse or lakehouse, and the cost envelope limits spend across them.
Figure 1: The layered guardrail model. The lower the layer, the less a prompt can change it
Each guardrail type controls one thing and maps to an OWASP risk. Each layer is who enforces it:
Agent layer: Your agent or application, its framework, and Amazon Bedrock.
Access layer: The tools between the agent and your data, such as MCP servers and AgentCore Gateway (a capability of Amazon Bedrock AgentCore), and the IAM policies on the identities those tools use.
Data layer: Amazon Redshift and, for lakehouse tables, AWS Lake Formation.
The following table lists the six guardrail types. Each row names the guardrail type, the main OWASP risk it reduces, and the layer and controls that enforce it.
The agent layer is the first filter, but it cannot be the only one. Most Amazon Bedrock Guardrails checks are model-based classifiers, some with a strength that you tune, so they catch most problems but not all. The guardrails that protect your data in Redshift therefore sit in the access and data layers, which apply fixed rules to the caller’s identity. You need both. AWS Identity and Access Management (IAM) policies decide which Redshift workgroups and APIs it can call, and Redshift and Lake Formation permissions decide what its SQL can touch. Fixed rules give the same answer whichever agent wrote the request, so a prompt injection that gets past the agent layer still cannot reach data that the agent’s identity is not granted.
Agentic analytics patterns on Amazon Redshift
Conversational analytics, the most common pattern, answers business questions from your data in self-service and managed delivery models. The others enrich data, take actions, or help administrators run the warehouse itself.
Scoped writes. Human approval for consequential ones
Operate
Administrators review and tune the warehouse with Kiro, Redshift skills, and the MCP Server review_cluster tool
Read-only. Changes ship as reviewed code
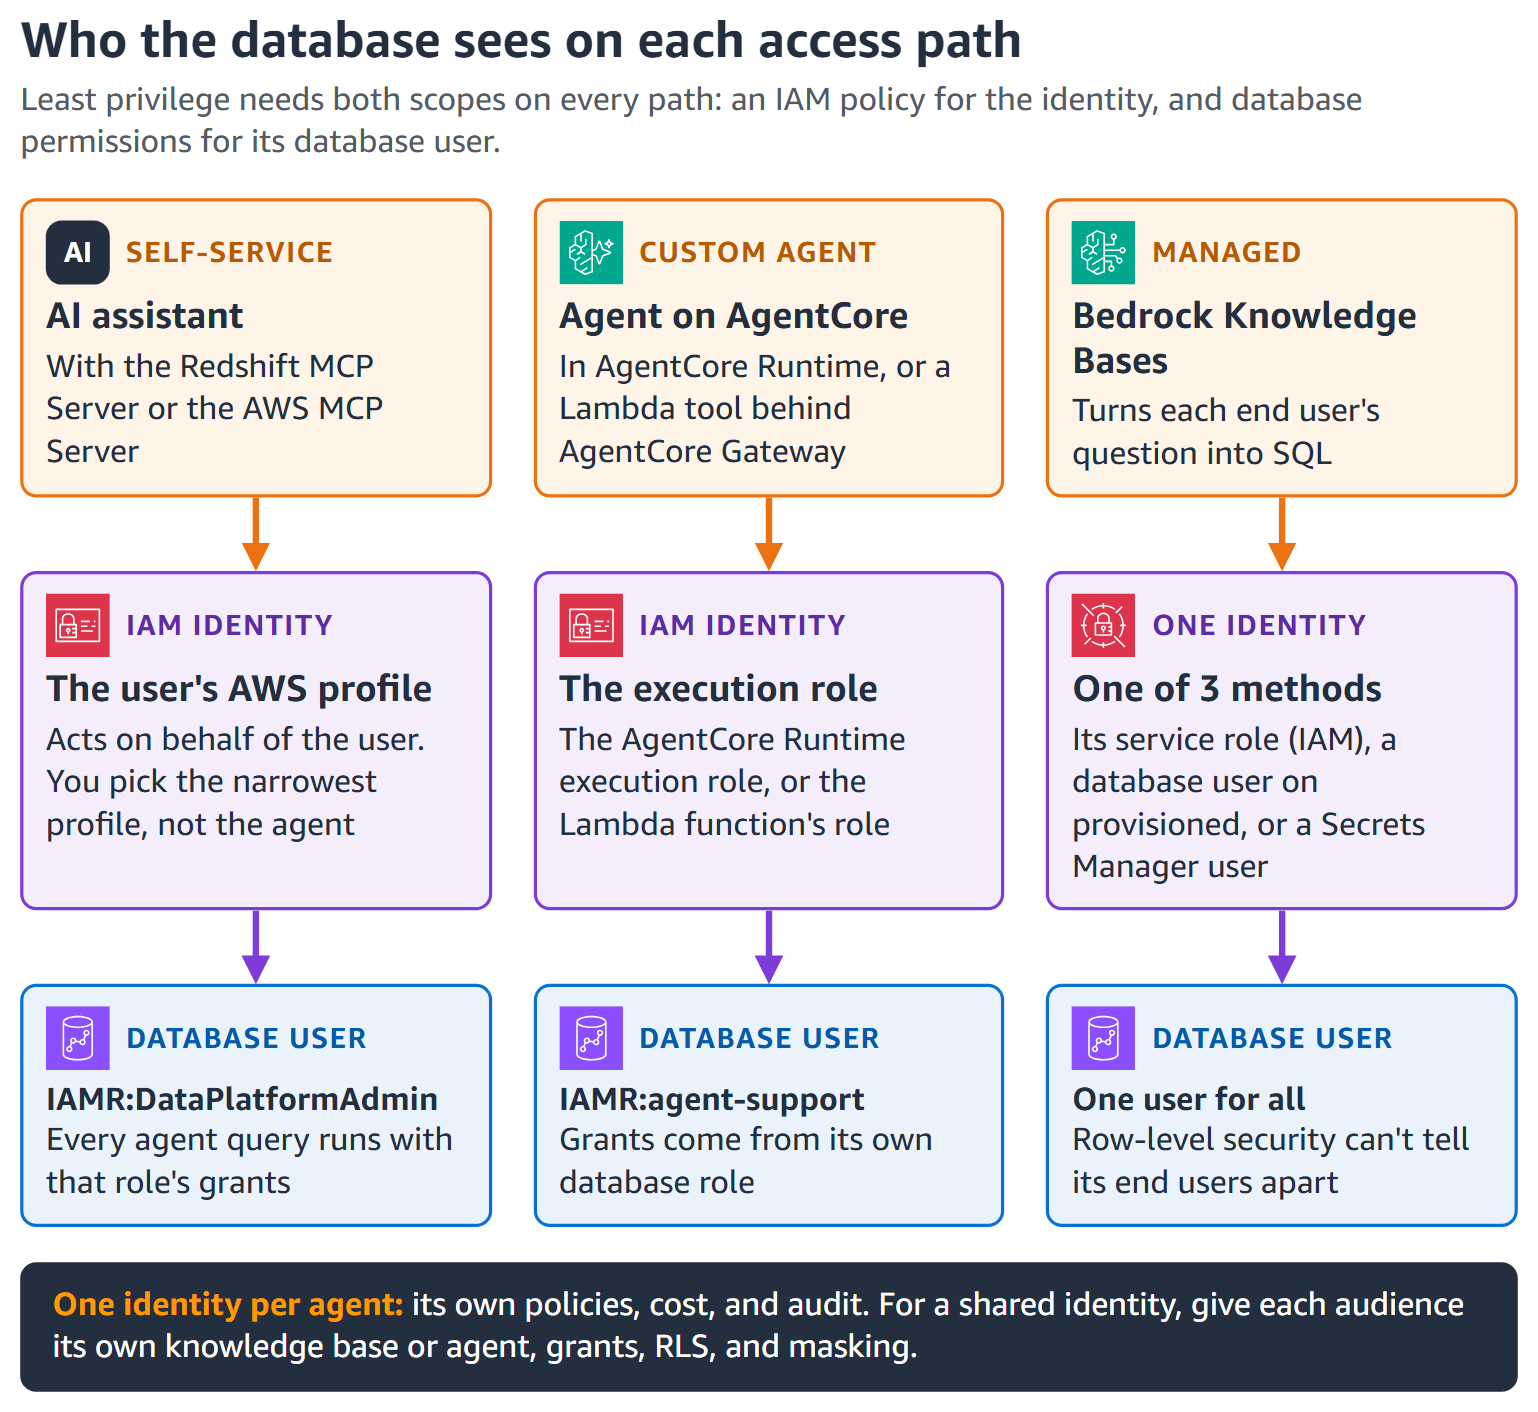
Every pattern needs the same two scopes for least privilege: IAM permissions that limit which workgroups and APIs an identity can call, and database permissions that limit what its SQL can read or change. What differs is which identity reaches Redshift:
Self-service (AI assistants with the Redshift MCP Server or AWS MCP Server). The AI assistant acts on behalf of the user, with the AWS profile in its MCP configuration. If your roles have different scopes, set up a profile for each and point the server at the narrowest one for the task, such as a read-only analyst role for sales questions. The setup steps are in access-layer/redshift-mcp-server and access-layer/aws-mcp-server in the aws-samples repository.
Redshift MCP Server: A user whose profile assumes a DataPlatformAdmin role runs every agent query as IAMR:DataPlatformAdmin, with that role’s grants. The server is read-only by default, and the agent can’t switch profiles. To use a broader profile, change it yourself in the MCP configuration.
AWS MCP Server: The agent can switch on each call among the profiles listed in the MCP Proxy for AWS configuration. List only the profiles you want it to use, and put the read-only one first so it’s the default. On provisioned clusters, a script can also choose a database user if the role allows redshift:GetClusterCredentials, so leave that permission out.
Both: The MCP configuration only controls the MCP tools. An agent that can run shell commands can use any profile on the machine, so the IAM roles and database grants are the real boundary.
SageMaker Data Agent: The agent runs SQL itself, including cells it fixes, as the signed-in person. Without trusted identity propagation, Redshift sees one IAMR:user-<id>@<project> database user per project member. With it, Redshift sees the person’s AWS IAM Identity Center user, so row-level security, masking, and grants apply to each person.
Custom agents, for example on Amazon Bedrock AgentCore. The database user comes from the role that calls the Data API: the AgentCore Runtime execution role, or the AWS Lambda function’s role behind AgentCore Gateway, such as IAMR:agent-support. If the agent acts for a specific person, use trusted identity propagation. The agent’s tool exchanges the person’s sign-in token through AWS IAM Identity Center, optionally federated with your external identity provider, and calls the Data API as that person. Redshift then applies their grants (writes included), row-level security, and masking, plus Lake Formation permissions if you enable that integration.
Managed (Amazon Bedrock Knowledge Bases). The knowledge base runs the SQL it generates as one identity. On Serverless workgroups and provisioned clusters, that is its service role with IAM or the user in an AWS Secrets Manager secret. Provisioned clusters also accept a named database user (authentication methods). Knowledge Bases can’t carry the actual user with trusted identity propagation, so when one identity serves many end users, row-level security can’t tell them apart. With one shared knowledge base, a West region manager and an East region manager query as the same database user, so both get every row that user can read. Instead, create one knowledge base or agent for each audience, such as one per sales region, and scope its role, grants, and row-level security policy to that audience.
Figure 2: Who Redshift sees on each access path
Decide how much agency to grant
Grant agency, what an agent can do, on two planes. The data plane is SQL on Redshift managed storage or Apache Iceberg tables, governed by Redshift and AWS Lake Formation permissions. The control plane is API calls that create, resize, manage, or delete infrastructure, governed only by IAM. The AWS Agentic AI Security Scoping Matrix bounds agency with permissions and autonomy with oversight. Following it, start read-only (Scope 1), then add scoped writes with a human in the loop for consequential ones (Scope 2). Keep agents off the control plane, and widen autonomy (Scopes 3 and 4) only within those boundaries.
Agent layer: Guide the request
The agent layer, mostly outside Redshift, is the first filter. Its controls run in your agent, Amazon Bedrock, and Amazon Bedrock AgentCore, so you set them up and pay for them there. These include the step, retry, and token limits that cap the agent’s own model spend.
Input. Bedrock Guardrails filters prompt injection attempts and denied topics, and ApplyGuardrail works with your choice of model.
Business context.Business context and skill assets in the AWS Glue Data Catalog tell agents which tables and joins to use. They are in preview in the US East (N. Virginia), US East (Ohio), US West (Oregon), and Europe (Ireland) Regions.
Agent configuration and oversight. Limit an agent’s tools before it runs. In Kiro, for example, the MCP configuration lists the tools to approve automatically (autoApprove) and the tools to hide from the agent (disabledTools). Add project instructions, and set step and retry limits in agent frameworks.
Access layer: Limit what the agent can call
The access layer decides which tools an agent can call and what each call can do. Redshift enforces its guardrails the same way for every prompt.
Data plane: A narrow tool surface on every path
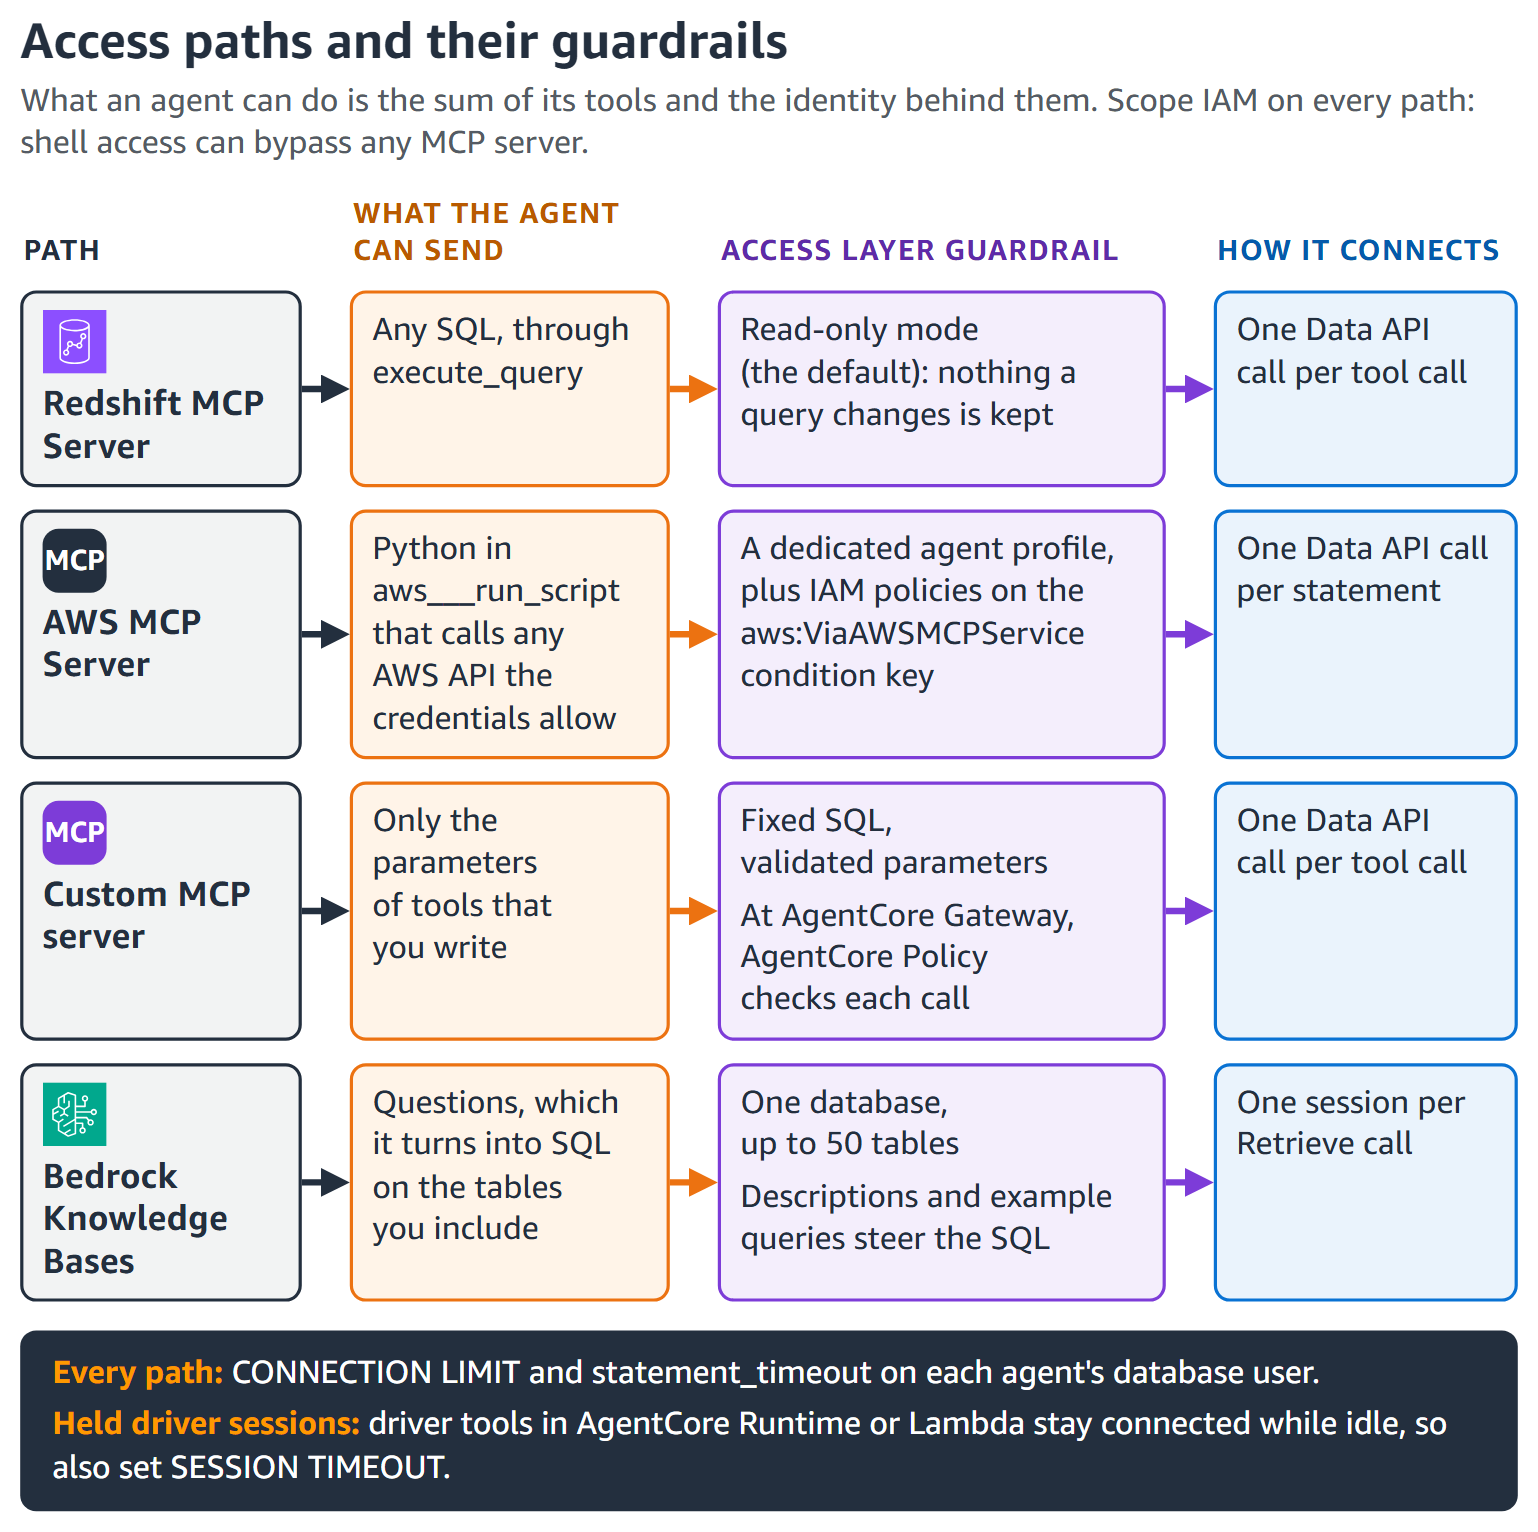
Figure 3 shows the tool guardrail each connection path needs, plus least-privilege IAM and database permissions. Each path has a worked example in the access-layer folder of the aws-samples repository, with setup, verification, and clean-up steps.
Figure 3: Access paths and their guardrails
Agents with shell access can bypass an MCP server with the AWS CLI, so scope IAM on every path. To allow only the AWS MCP Server path, see AWS MCP Server only, later in this section.
Discover lets the agent list workgroups. It uses "Resource": "*" because ListWorkgroups doesn’t support resource-level permissions, so it can’t limit where SQL runs.
RunSqlOnOneWorkgroup lets the agent sign in and run SQL on one workgroup only. This is the statement that limits where SQL runs. It includes redshift-data:BatchExecuteStatement, which the Redshift MCP Server needs before it can run writes or named transactions. Without that action, the server stays read-only by refusing writes itself. With it, writes still need ACCESS_MODE=read-write in the MCP configuration, which is off by default, and the agent’s database grants still limit what a write can change.
ReadOwnStatements lets the agent check status and read results only for statements it ran itself.
Custom MCP server: Tools that run fixed SQL. Expose only tools that each run one fixed, parameterized statement against a curated view, under the server’s own IAM role with SELECT on that view only. Have each tool set a fixed StatementName and SQL comment, so AWS CloudTrail and query history name the tool. In the sample server (access-layer/custom-mcp-server/sales_metrics_mcp.py), the agent supplies only a sales region, which the server checks against an allowed list, so prompt injection can at most make the tool query a different allowed region.
AWS MCP Server: Scope the credentials, not the script. Its aws___run_script sends SQL through the Data API as the caller’s mapped database user, so an administrator profile means administrator access. Four guardrails close that gap:
A dedicated agent profile in the MCP Proxy for AWS, for an agent role with read-only grants.
No way to switch database users. Allow redshift-serverless:GetCredentials or redshift:GetClusterCredentialsWithIAM, not redshift:GetClusterCredentials or Secrets Manager secrets, which let a caller choose another user.
Agent workgroups only. A service control policy in AWS Organizations denies Data API SQL through AWS managed MCP servers unless the workgroup is tagged agent-access=true. The same statement also works in an IAM policy or permissions boundary. SCPs skip the management account, so test on a sandbox OU first:
AWS MCP Server only. To stop the agent’s shell from going around the server, deny redshift-data:* on the agent role unless the call comes through it. Also deny direct driver sign-in when aws:ViaAWSService is false: redshift-serverless:GetCredentials, redshift:GetClusterCredentialsWithIAM and redshift:GetClusterCredentials, plus GetIdentityCenterAuthToken when you use trusted identity propagation (access-layer/aws-mcp-server/deny-data-api-outside-aws-mcp.json). Attach it to agent roles or permission sets, not as an SCP. IAM can’t tell the local Redshift MCP Server from the AWS CLI, so on that path read-only database grants are the boundary:
Scope every write, and keep a human in the loop where it matters
Give an agent one scoped tool per action, never a generic write tool. A write can run on its own when its tool limits it to one validated, low-impact action, so approvals don’t slow routine work. Consequential, irreversible, or above-threshold writes need a human in the loop:
Mechanism
How it works
Can the agent bypass it?
Approve as data (recommended for data writes)
The tool records a request. A people-only identity approves it
No: Redshift enforces it
Approve in the agent
The framework asks a person first
Depends on the framework
Approve as code review
Schema and infrastructure changes ship as reviewed code
No: your pipeline enforces it
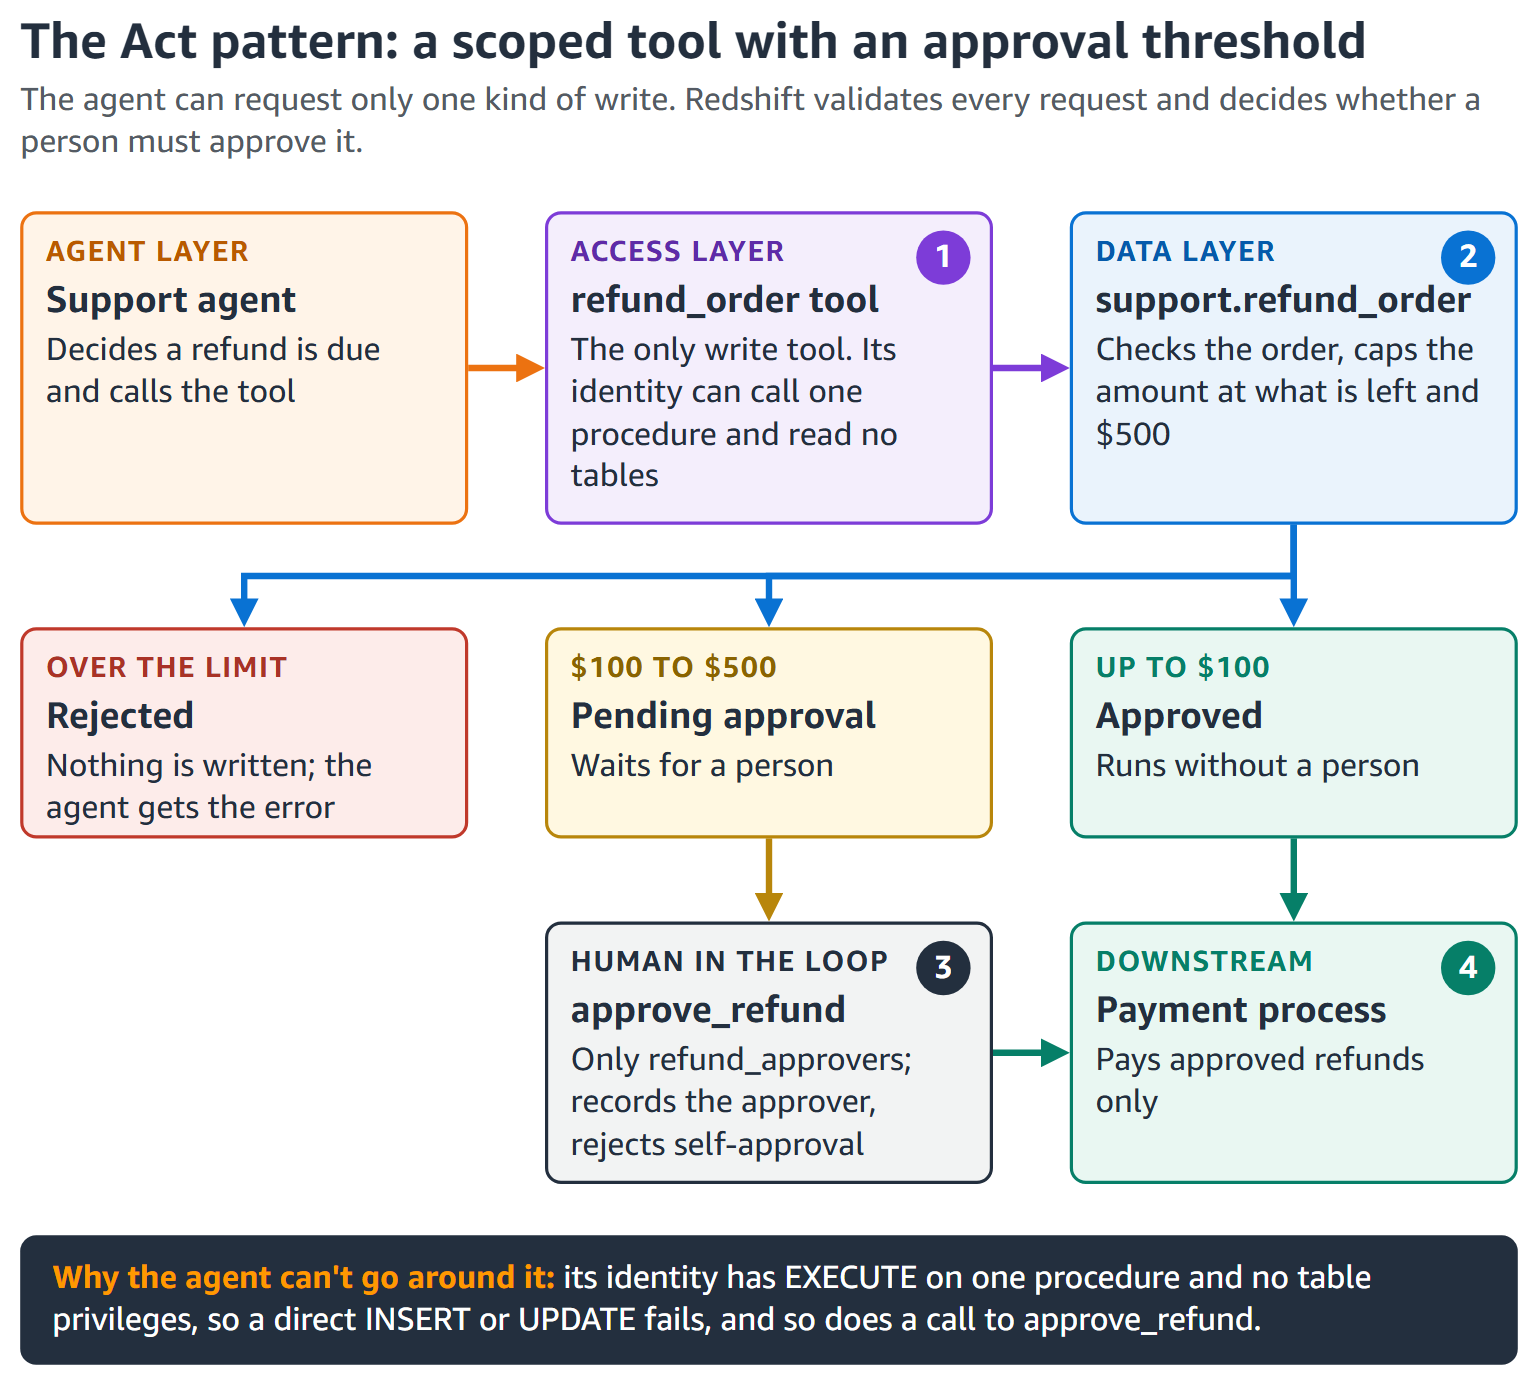
In the Act pattern, an agent writes to Redshift as part of a workflow, such as issuing a refund. Figure 4 shows how it combines both kinds of write:
The agent’s only write tool, refund_order, runs as an identity that can only EXECUTE one procedure.
The SECURITY DEFINER procedure checks the order and caps the amount at the remaining refundable amount and $500, locking support.refunds against concurrent over-refunds. A failed check writes nothing and returns an error the agent can report.
Refunds up to $100 are approved. Larger ones wait for the refund_approvers role, through a second procedure that rejects self-approval.
A payment process pays approved refunds only.
Figure 4: A scoped action tool, with human approval above a threshold
The procedures and grants are in act-refund/refund_procedures.sql. Expose refund_order as its own tool, under an identity separate from the agent’s read path, so the read identity has no write privileges. Scheduled writes that no agent starts, such as a nightly Enrich job that labels tickets with Redshift ML, need a different control. Review the job’s SQL once before you deploy it, then run it under its own identity that no agent can use.
Control plane: Keep infrastructure changes out of agents’ reach
Control plane calls skip database grants, so IAM is the only gate, and an AI assistant’s credentials often reach its shell and the AWS CLI too.
Give every AI assistant a scoped identity. Run Kiro and other AI assistants, and their MCP servers, under an agent-role AWS profile with read-only control plane actions and a permissions boundary. Don’t allow redshift:Get*, which includes GetClusterCredentials. Share the profile through one AWS IAM Identity Center permission set (access-layer/shared/aws-config-example.ini). Role chaining caps sessions at 1 hour.
Deny infrastructure changes through managed MCP servers. With the aws:ViaAWSMCPServicecondition key, a service control policy can deny create, delete, modify, resize, pause, resume, reboot, restore, and tagging actions made through an agent but not directly (access-layer/shared/deny-infra-changes-through-agents.json). Tagging matters because the data plane deny trusts the agent-access tag.
Data layer: Decide what the agent can reach
The data layer decides what an agent can actually reach, on every query. As the Redshift MCP Server documentation puts it, “The database user’s privileges are the security boundary, not this server.”
Give every agent its own identity: One IAM role, database user, and database role. The IAM role agent-support signs in through the Data API as IAMR:agent-support. On Redshift Serverless, a RedshiftDbRoles tag can grant its database role at sign-in (the aws-samples repository shows the tag). Agents acting for a person can use trusted identity propagation. Grant the role after the user’s first sign-in:
-- One database role per agent: privileges go to the role, never to the user
CREATE ROLE agent_support;
GRANT USAGE ON SCHEMA sales TO ROLE agent_support;
GRANT SELECT ON sales.orders, sales.payments TO ROLE agent_support;
GRANT ROLE agent_support TO "IAMR:agent-support";
Row-level security (RLS) filters rows only on tables you attach it to and makes a table default-deny, so attach policies for other roles first.
Column privileges remove columns, such as email.
Dynamic data masking transforms values, such as a card’s last four digits.
Limit what agents can discover. Turn on metadata security so catalog views and SHOW list only objects the role can access, so agents cannot plan around hidden tables (superusers and ACCESS CATALOG roles see all). Test on non-production first:
ALTER SYSTEM SET metadata_security = true; -- superuser only; applies to the whole cluster or workgroup
GRANT ACCESS CATALOG TO ROLE agent_monitoring; -- a monitoring role that must still see every object
Extend the rules to the lakehouse and other warehouses, so no path skips your filters. Redshift enforces Lake Formation permissions on Iceberg tables, including Amazon S3 Tables (a capability of Amazon S3), and federated permissions carry RLS and masking to an agent warehouse. Plain datashares do not carry RLS filters.
Treat free text as untrusted: Keep Redshift ML instructions in the static PROMPT prefix, and pass row text only as input.
Allow only approved models. The model’s IAM role decides at inference time, so allow bedrock:InvokeModel only on approved model ARNs. By default only superusers can create models. Grant CREATE MODEL to an ML platform role, with ASSUMEROLE ... FOR CREATE MODEL only on approved IAM roles.
Test as the agent: Superusers and sys:secadmin bypass RLS.
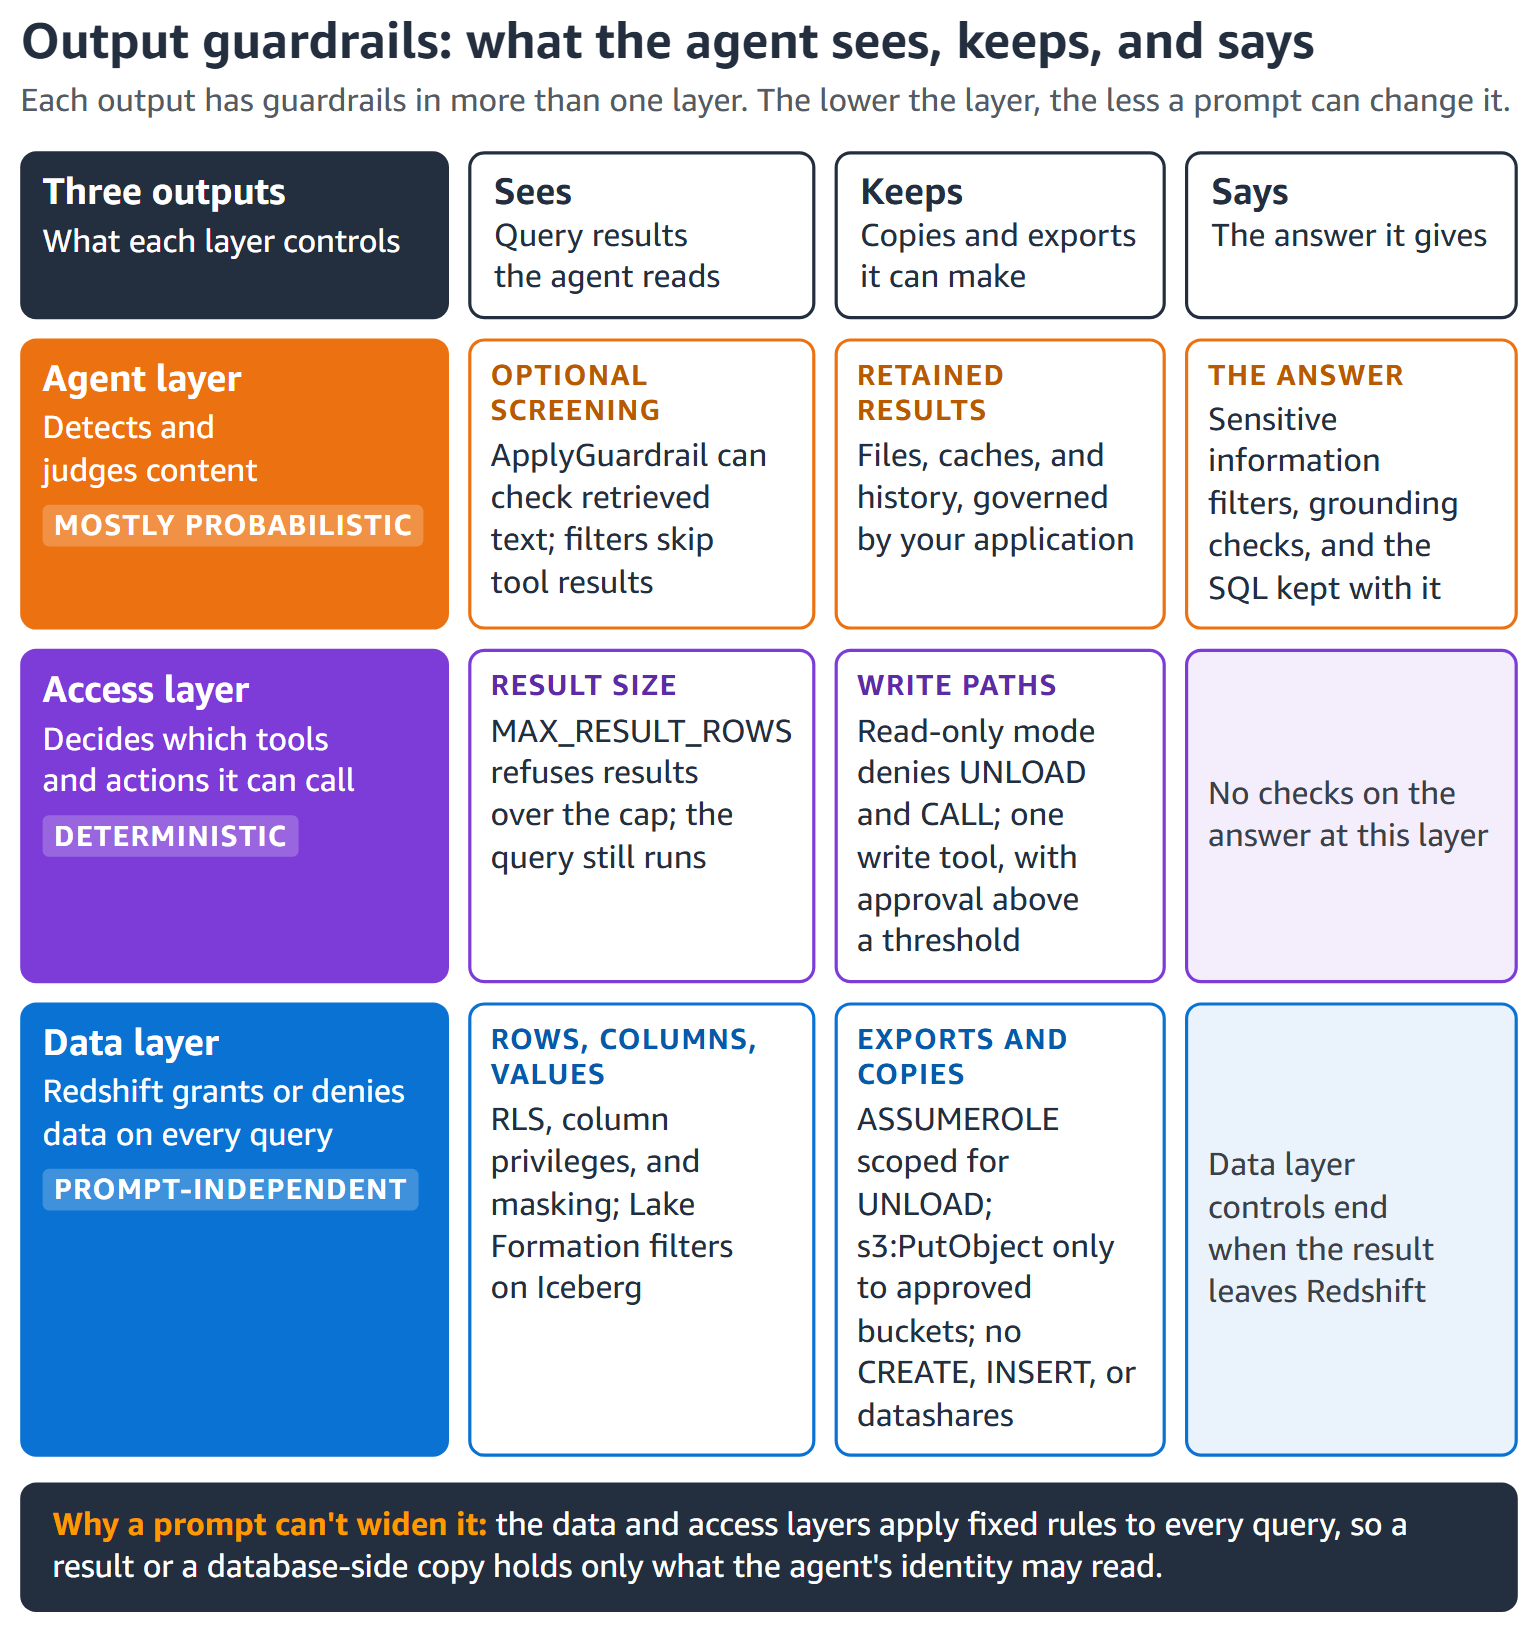
Output guardrails: What the agent sees, keeps, and says
An agent has three outputs: results it reads, copies it keeps, and its answer. Redshift controls what enters the agent and its database-side copies. The application and agent layer govern the rest.
What the agent sees and says
The data layer’s policies double as output guardrails: results hold only permitted rows and readable columns, masked values stay masked, and Lake Formation filters do the same for Iceberg tables.
Cap result size too: provisioned clusters can abort on return_row_count, and the Redshift MCP Server’s MAX_RESULT_ROWS (1,000 by default) refuses larger results, protecting the context window, not compute.
Data-layer controls end when results leave Redshift, so check the answer too: Bedrock Guardrails can mask PII and flag ungrounded answers, and the generated SQL makes the answer traceable.
What the agent keeps: Database-side exports and copies
A copy starts with none of the source table’s policies, so treat every database-side write path as an output path:
Export path
Guardrail
UNLOAD to Amazon S3
REVOKE ASSUMEROLE ON ALL FROM PUBLIC FOR ALL (which also blocks COPY and CREATE MODEL). Grant ASSUMEROLE ... FOR UNLOAD to pipeline roles only
CETAS and INSERT into external tables
Agent roles own no external schemas
Writes to Apache Iceberg tables
No Lake Formation write permissions for agent-facing roles
CTAS, SELECT INTO, and INSERT ... SELECT
REVOKE CREATE ON SCHEMA public FROM PUBLIC. No CREATE or INSERT for agents
Datashares
No datashare privileges for agent roles
The MCP Server’s read-only mode denies UNLOAD and CALL, but other paths bypass it, so privileges are the durable line (data-layer/exports-and-copies.sql). Audit exports in SYS_UNLOAD_HISTORY, SYS_QUERY_HISTORY, and CloudTrail S3 data events.
Figure 5 summarizes which layer controls each output.
Figure 5: What the agent sees, keeps, and says, and which layer controls each
The cost envelope: Predictable by design
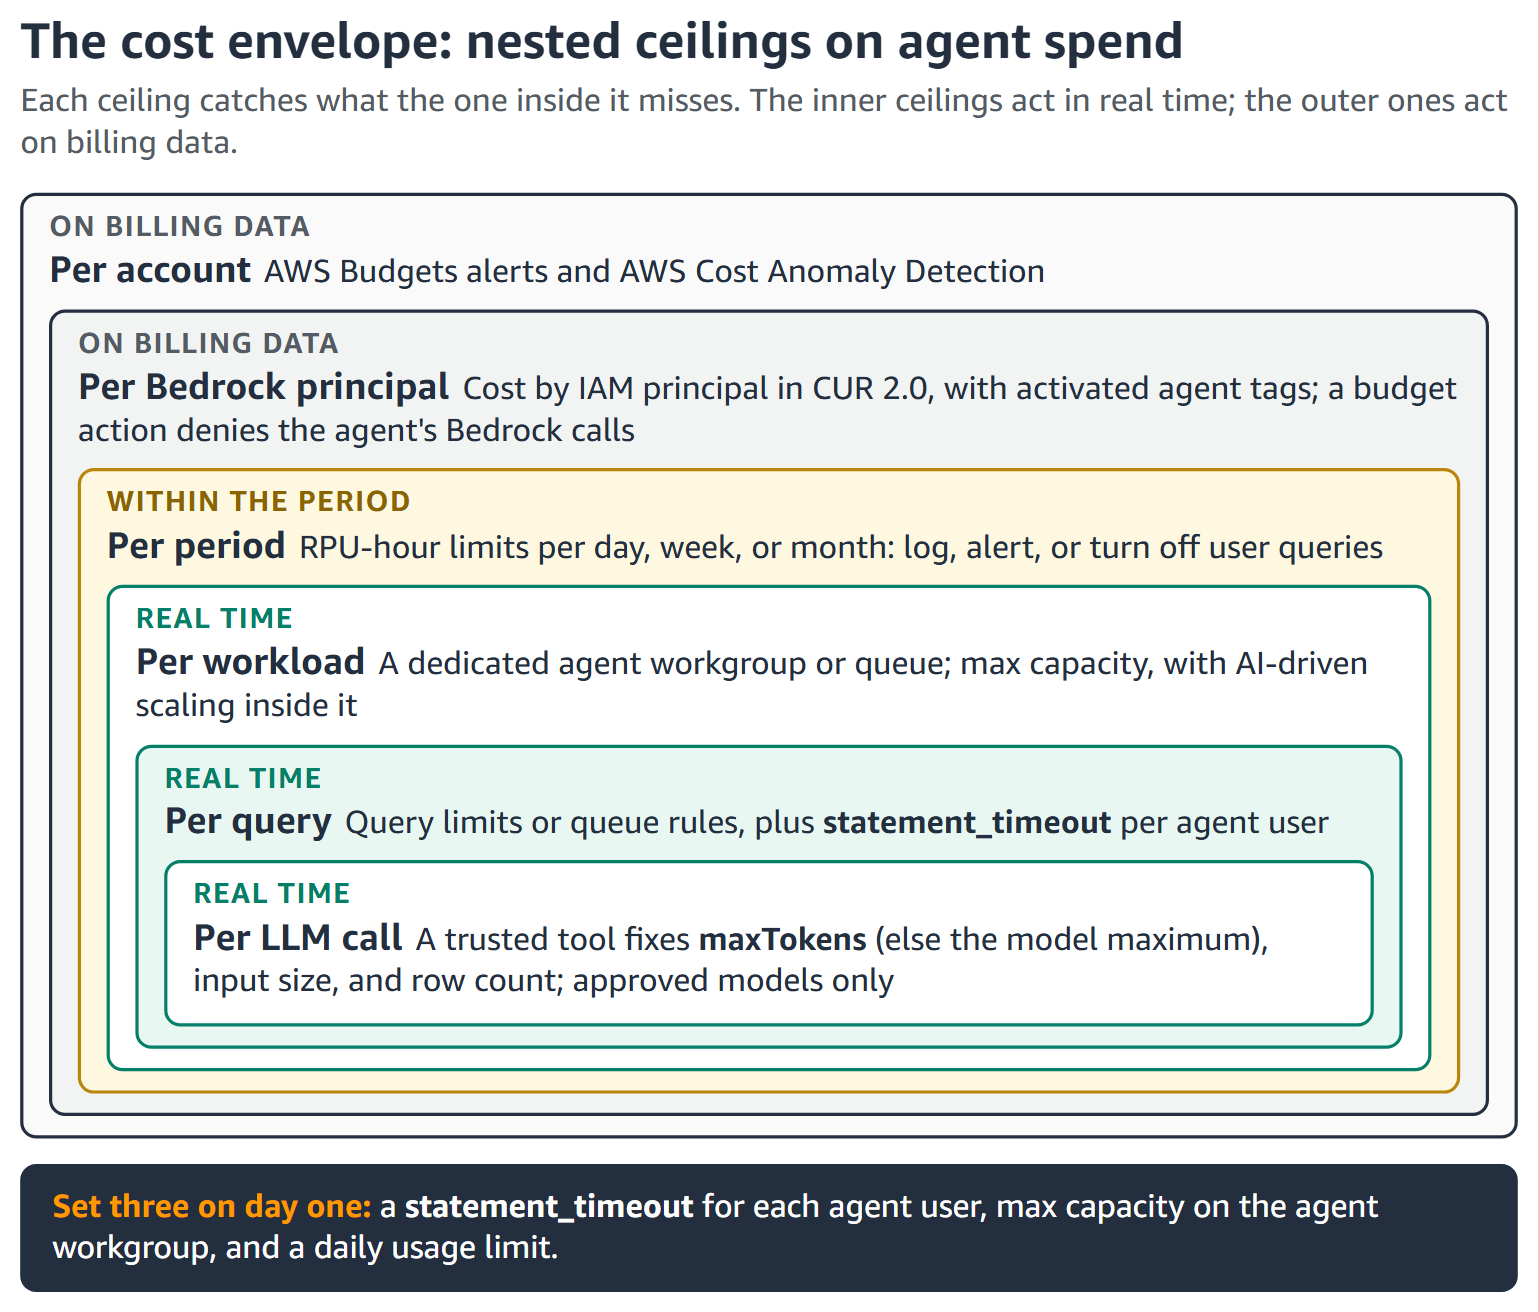
Each agent question has three cost parts (Figure 1): model tokens at Bedrock rates, query compute on Redshift provisioned clusters or Amazon Redshift Serverless RPUs that you already pay for (older RA3 and DC2 clusters also bill lakehouse scans per terabyte), and data at rest. These compute guardrails are part of Redshift, and you pay only for the Redshift compute your queries use:
Set three ceilings on day one (Figure 6): a per-statement timeout for each agent user, max capacity on the agent workgroup, and a daily usage limit. Queue rules are checked every 10 seconds, so the timeout is the tighter cap.
Figure 6: The cost envelope. Each ceiling catches what the one inside it misses
Max capacity and the usage limit do different jobs (see Billing for on-demand compute capacity). Max capacity caps RPUs. The usage limit logs, alerts, or stops user queries once the period’s RPU-hours are used (cost-envelope/serverless-ceilings.sh). emit-metric only publishes a metric. Alarm on it, or choose Alert on the AWS Management Console.
Each Serverless workgroup or RG cluster accepts at most 2,000 connections. In our tests, Data API tools opened one connection per call, but an idle open driver transaction kept Serverless compute running until the 1-hour timeout. On Serverless, deny redshift-serverless:GetCredentials when aws:ViaAWSService is false. In our tests, this blocked driver sign-in, not direct Data API calls. On each non-superuser agent user (superusers ignore connection limits), set:
ALTER USER "IAMR:agent-support" SET statement_timeout TO 120000;
ALTER USER "IAMR:agent-support" CONNECTION LIMIT 10 SESSION TIMEOUT 300; -- size the limit to the agent's concurrency
Spend less per answer
Reuse work: The result cache, composition for new queries, and materialized views for repeated joins.
Right-size the engine. For lake-heavy agents, RG instances cost 30% less per vCPU than RA3, with no per-terabyte scanning charges.
Spend and store less. Every byte saved is a byte agents don’t read. For local tables, keep ENCODE AUTO so Redshift selects optimal column compression by data type. Iceberg tables use zstd compression by default, helping reduce storage and scan costs (cost-envelope/storage-compression.sql).
Control model spend per agent
Bedrock attributes inference cost to the calling IAM principal (Introducing granular cost attribution for Amazon Bedrock). Since Redshift ML calls Bedrock with the role in CREATE EXTERNAL MODEL, give each agent its own role. A trusted tool, the only identity allowed to run the model, fixes maxTokens and bounds input (cost-envelope/model-spend-summarizer.sql), and a budget action can deny bedrock:InvokeModel and bedrock:InvokeModelWithResponseStream to the role as a period-level brake, not a real-time stop.
Per-agent users make SYS_QUERY_HISTORY a compute ledger. Tag both ledgers per AGENTCOST05-BP01. Because the Redshift MCP Server in read-only mode refuses SETquery_group, attribute by IAM role.
Observe and prove
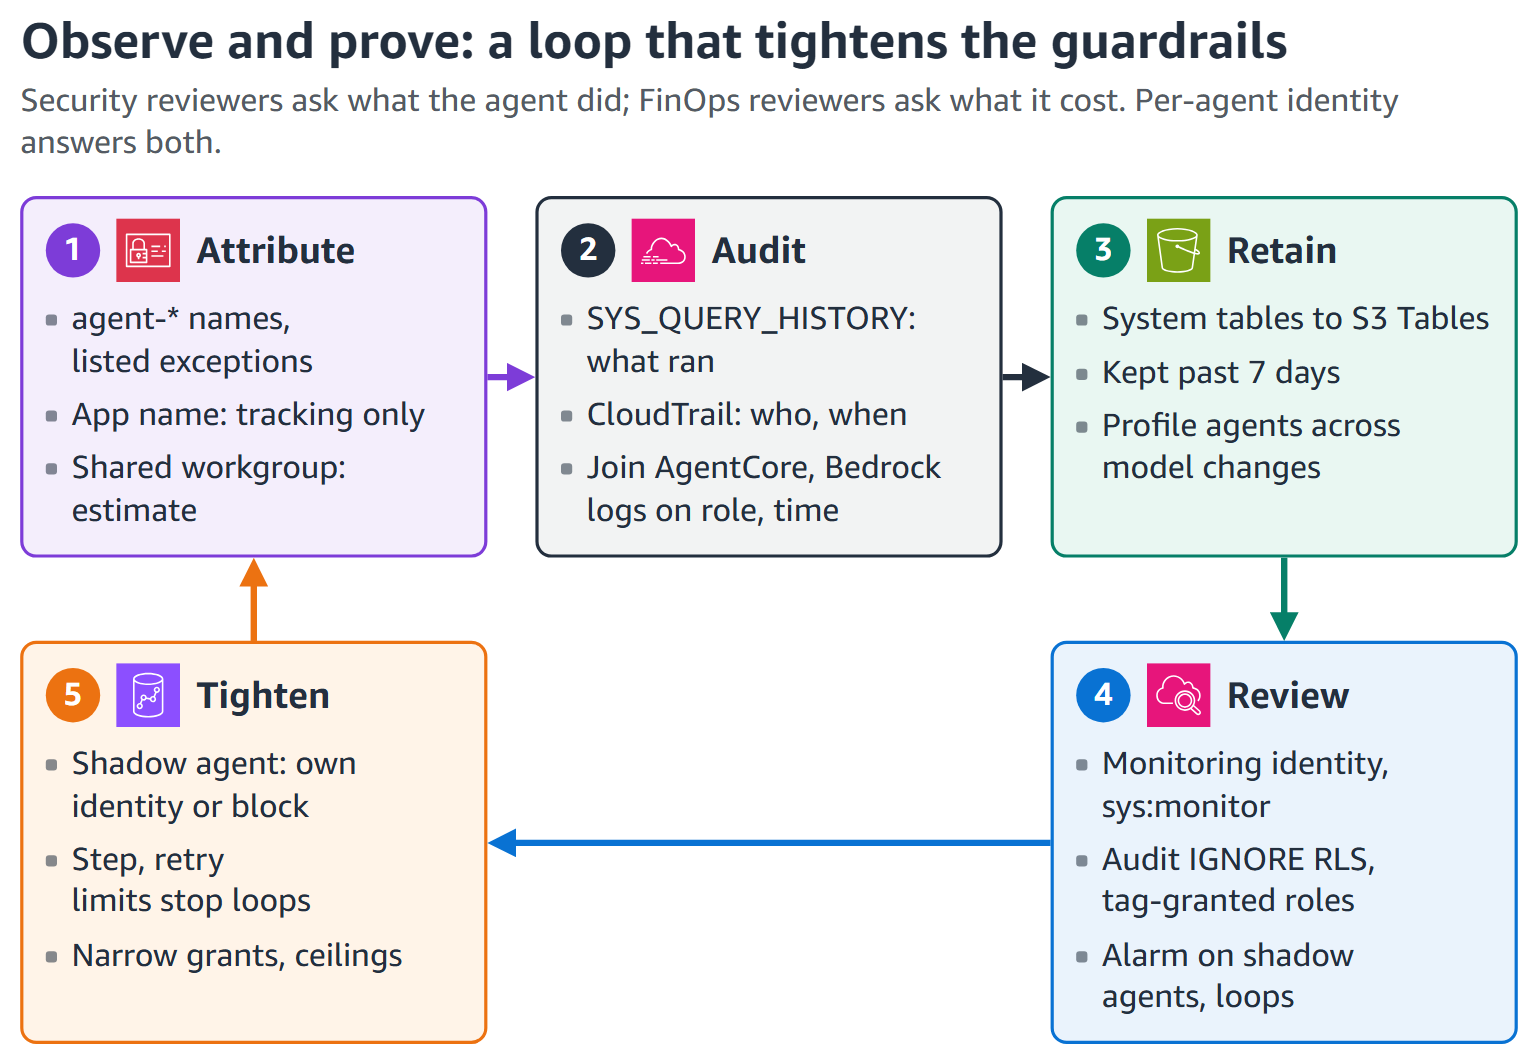
Security reviewers ask what the agent did, and FinOps reviewers ask what it cost. Per-agent identity answers both.
Figure 7 shows how the following records feed back into tighter guardrails.
Figure 7: The observe and prove loop
What ran, and who called it. SYS_QUERY_HISTORY lists each agent user’s queries, and an agent- prefix on every agent identity lets one filter cover them. CloudTrail adds who and when. With trusted identity propagation, both identify the person.
Find shadow agents, which are MCP calls from an identity without the agent- prefix. The application_name setting and the CloudTrail userAgent or userIdentity.invokedBy fields mark MCP traffic (observe/detection/shadow-agents.sql).
In this post, we showed how the layered guardrail model runs agentic analytics on Amazon Redshift, with most controls built into Redshift. The access layer keeps a human in the loop for consequential writes, and the data layer decides what each query can reach.
Bound the data. Grant only needed tables and columns, attach RLS and masking, revoke ASSUMEROLE and CREATE from PUBLIC, and test metadata security on non-production first.
Bound the spend. Set a statement timeout, max capacity, and a daily usage limit, and test that the usage-limit alarm fires.
Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3), deliver a cloud object store with built-in Apache Iceberg support and streamline storing tabular data at scale. When you integrate them with dbt and AWS Glue, you can run SQL-based data transformations with the reliability and performance of a modern lakehouse, bringing software engineering best practices to the data space.
This post demonstrates how to configure and implement dbt transformations using Amazon S3 Tables with the dbt-glue adapter. Starting with version 1.12.4, the dbt-glue adapter adds incremental merge support for S3 Tables, which the patterns in this post build on. We cover the specific configuration requirements for the dbt-glue adapter and practical implementation patterns built on S3 Tables incremental models: the merge strategy to keep the latest state per record and the append strategy to build an audit-friendly change history.
Example scenario
In this walkthrough, we simulate an ecommerce system that tracks customer profiles and their orders. We first run the pipeline against an initial dataset, then simulate an update to the upstream source data and run it again to demonstrate incremental updates.
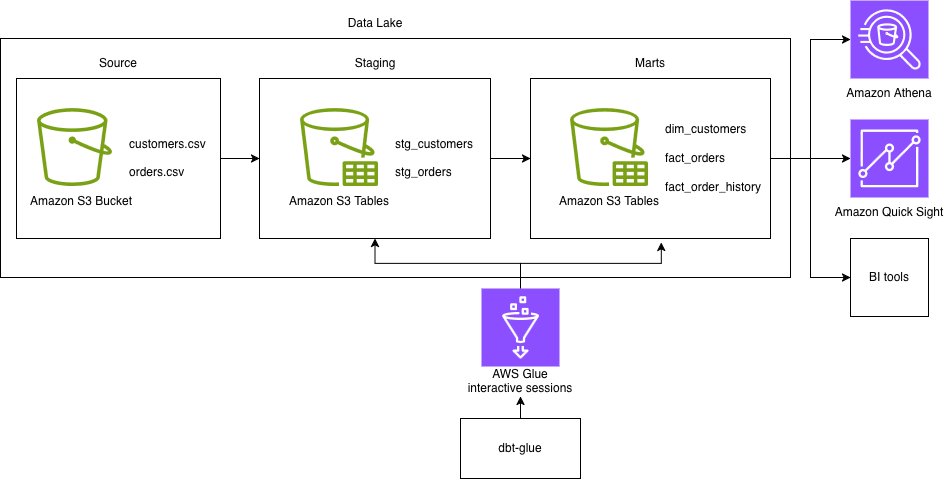
Our example scenario follows a data pipeline architecture that uses S3 Tables throughout. Raw ecommerce data (customers.csv and orders.csv) lands in a regular S3 bucket as comma-separated values (CSV). dbt then transforms it through two layers of S3 Tables. A staging layer cleanses and standardizes each source, and a mart layer produces analytics-ready dimension and fact tables. You can query the resulting mart data from a variety of analytics and business intelligence (BI) tools such as Amazon Athena and Amazon Quick Sight. In this post, we query it from Athena.
The mart layer demonstrates two incremental strategies side by side: the fact_orders model uses merge to keep the latest state per order, while fact_order_history uses append to accumulate a full change history.
The data pipeline flow looks like the following chart:
Source Data (Regular S3 - CSV)
    └─ customers.csv, orders.csv
    ↓
Staging Models (S3 Tables)
    ├─ stg_customers
    └─ stg_orders
    ↓
Mart Models (S3 Tables)
    ├─ dim_customers
    ├─ fact_orders                (incremental with merge --- latest state per order)
    └─ fact_order_history         (incremental with append --- change history)
    ↓
Consumption Layer (Athena, Quick Sight, BI tools)
The following diagram shows the architecture behind this pipeline: dbt-glue submits each model as a Spark SQL statement to an AWS Glue interactive session, which reads from the raw S3 bucket and writes the staging and mart tables as S3 Tables within the same data lake.
Figure 1: Architecture of the dbt transformation pipeline on Amazon S3 Tables with AWS Glue
Prerequisites
Before you begin, make sure that you have the following prerequisites:
In this section, you set up the AWS infrastructure that dbt-glue needs: an S3 table bucket and namespace to hold your dbt models, and an AWS Glue database for your source data.
First, set your environment variables. Replace YOUR_ACCOUNT_ID, YOUR-REGULAR-BUCKET, and YOUR_Glue_Role_ARN with your data:
Note that the S3 Tables namespace is where the S3 Tables corresponding to your dbt models will be created. This is different from regular S3 buckets. Because the “Integration with AWS analytics services” option for S3 Tables is enabled, creating the namespace automatically creates a corresponding AWS Glue database. Verify that it exists in the next step:
In this section, you create sample ecommerce data to transform with dbt: two CSV files (customers and orders), upload them to a general purpose S3 bucket, and register them as AWS Glue tables that your dbt models can read from.
Note: All sample data in this post is synthetic. It was generated to mimic realistic patterns for demonstration purposes only and doesn’t represent any real individuals or transactions.
Complete following steps to create a sample dataset:
Create a directory for sample data and save the following two CSV files: customers.csv:
Create the bucket for source data if it doesn’t exist, and upload the CSV files to the S3 bucket. Replace YOUR-SOURCE-DATA-BUCKET with your bucket name.
The dbt CLI is a command-line interface for running dbt projects. It’s free to use and available as an open source project. Before installing dbt-core, make sure your Python version is 3.10, 3.11, or 3.12.
Install dbt and the dbt CLI with the following code:
Install the dbt-glue adapter with the following code:
$ pip3 install --no-cache-dir dbt-glue
Note that you need to install dbt-glue 1.12.4 or higher, which adds support for incremental append and merge models on S3 Tables.
Create a dbt project
In this section, you create a new dbt project using dbt init, which generates the standard directory structure (such as models, macros, and tests) that you will populate with the S3 Tables models in the next sections.
Run the dbt init command to create and initialize a new empty dbt project.
$ dbt init
For a project name, enter dbt_glue_s3_tables.
For a database, choose [1] glue.
Please ignore dbt_project.yml file [ERROR not found] message as we are going to create it in the next step.
Configure dbt profile
The dbt profile configuration is critical for S3 Tables integration. In this section, you create a dbt profile that connects to AWS Glue Interactive Sessions and configures Spark to read and write S3 Tables through the Iceberg catalog, then validate the connection with dbt debug.
Create ~/.dbt/profiles.yml with the following structure:
Run the following command to validate the configurations:
cd dbt_glue_s3_tables
dbt debug --profiles-dir ~/.dbt/
Expected output is Connection test: [OK connection ok].
Configure dbt project
The dbt_project.yml configuration determines which models use S3 Tables. Create or update dbt_glue_s3_tables/dbt_project.yml with the following structure:
name: 'dbt_glue_s3_tables'
version: '1.0.0'
config-version: 2
profile: 'dbt_glue_s3_tables'
model-paths: ["models"]
test-paths: ["tests"]
macro-paths: ["macros"]
models:
  dbt_glue_s3_tables:
    # S3 Tables for staging
    staging:
      +materialized: table
      +file_format: 's3tables'  # S3 Tables for staging
      +table_properties:
        'format': 'iceberg'
        'write.format.default': 'parquet'
        'write.parquet.compression-codec': 'snappy'

    # S3 Tables for marts
    marts:
      +materialized: table
      +file_format: 's3tables'  # S3 Tables for marts
      +table_properties:
        'format': 'iceberg'
        'write.format.default': 'parquet'
        'write.parquet.compression-codec': 'snappy'
Create dbt models
In this section, you build out the full model layer: a sources.yml that registers your raw AWS Glue tables, two staging models that clean and prepare the customer and order data, and three mart models that turn those staged data into a dimension table and two fact tables, one using incremental merge and one using incremental append.
First, create sources.yml defines your raw data tables:
Delete the example folder under dbt_glue_s3_tables/models. This is an example folder created by default and unnecessary now.
Define source tables in models/sources.yml with the following structure:
This sources.yml defines your raw data tables, so you can reference them with the {{ source() }} function in your models. With this file, you can also define data tests like unique, not_null, and referential integrity checks in one central place.
Second, create the staging and mart models. Staging models are where you unpack and transform raw data. Mart models are what downstream consumers actually query.
Create models/staging/stg_customers.sql:
-- Staging model as S3 Tables with incremental merge
{{ config(
    materialized='incremental',
    incremental_strategy='merge',
    unique_key='customer_id',
    on_schema_change='sync_all_columns',
    file_format='s3tables'
) }}

SELECT
    customer_id,
    LOWER(TRIM(email)) AS email,
    first_name,
    last_name,
    CAST(registration_date AS DATE) AS registration_date,
    customer_segment
FROM spark_catalog.{{ source('raw_ecommerce', 'customers') }}
WHERE customer_id IS NOT NULL
stg_customers.sql reads from the raw customers source, applies light cleansing (email normalization, date casting, null filtering), and writes to S3 Tables using an incremental merge on customer_id to update existing records rather than duplicating them.
Create models/staging/stg_orders.sql:
-- Staging model as S3 Tables with incremental merge
{{ config(
    materialized='incremental',
    incremental_strategy='merge',
    unique_key='order_id',
    on_schema_change='sync_all_columns',
    file_format='s3tables'
) }}

SELECT
    order_id,
    customer_id,
    CAST(order_date AS DATE) AS order_date,
    CASE
        WHEN LOWER(TRIM(order_status)) = 'completed'  THEN 'completed'
        WHEN LOWER(TRIM(order_status)) = 'shipped'    THEN 'shipped'
        WHEN LOWER(TRIM(order_status)) = 'processing' THEN 'processing'
        WHEN LOWER(TRIM(order_status)) = 'cancelled'  THEN 'cancelled'
        ELSE 'unknown'
    END AS status,
    CAST(order_amount AS DECIMAL(10,2)) AS total_amount,
    EXTRACT(YEAR  FROM CAST(order_date AS DATE)) AS order_year,
    EXTRACT(MONTH FROM CAST(order_date AS DATE)) AS order_month,
    CAST(updated_at AS TIMESTAMP) AS updated_at
FROM spark_catalog.{{ source('raw_ecommerce', 'orders') }}
WHERE order_id IS NOT NULL
stg_orders.sql reads from the raw orders source, normalizes status to a fixed set of values (defaulting to unknown for anything unexpected), casts order_date, total_amount, and updated_at to their proper types, and derives order_year and order_month for downstream partitioning.
Create models/marts/dimensions/dim_customers.sql:
-- Dimension table using S3 Tables
{{ config(
    materialized='table',
    file_format='s3tables',
    partition_by=['registration_year'],
    table_properties={
        'format': 'iceberg',
        'write.format.default': 'parquet'
    }
) }}

SELECT
    customer_id,
    email,
    first_name,
    last_name,
    registration_date,
    YEAR(registration_date) as registration_year,
    customer_segment,
    CASE
        WHEN customer_segment = 'Premium' THEN 1
        WHEN customer_segment = 'Regular' THEN 2
        ELSE 3
    END as segment_priority,
    CURRENT_TIMESTAMP() as dbt_updated_at
FROM {{ ref('stg_customers') }}
Create models/marts/facts/fact_orders.sql:
-- Fact table using S3 Tables with incremental merge
{{ config(
    materialized='incremental',
    file_format='s3tables',
    incremental_strategy='merge',
    unique_key='order_id',
    partition_by=['order_year', 'order_month'],
    table_properties={
        'format': 'iceberg',
        'write.format.default': 'parquet'
    }
) }}

SELECT
    o.order_id,
    o.customer_id,
    o.order_date,
    YEAR(o.order_date)  AS order_year,
    MONTH(o.order_date) AS order_month,
    o.status,
    o.total_amount,
    c.customer_segment,
    c.segment_priority,
    CURRENT_TIMESTAMP() AS dbt_updated_at
FROM {{ ref('stg_orders') }} o
LEFT JOIN {{ ref('dim_customers') }} c
  ON o.customer_id = c.customer_id
Create models/marts/facts/fact_order_history.sql:
-- Fact table using S3 Tables with incremental append
{{ config(
    materialized='incremental',
    file_format='s3tables',
    incremental_strategy='append',
    partition_by=['event_year', 'event_month'],
    table_properties={
        'format': 'iceberg',
        'write.format.default': 'parquet'
    }
) }}

SELECT
    order_id,
    customer_id,
    status,
    order_date,
    total_amount,
    updated_at,
    CURRENT_TIMESTAMP() AS recorded_at,
    YEAR(updated_at)    AS event_year,
    MONTH(updated_at)   AS event_month
FROM {{ ref('stg_orders') }}

{% if is_incremental() %}
    WHERE updated_at > (SELECT MAX(updated_at) FROM {{ this }})
{% endif %}
Run the dbt project
Now it’s time to run the dbt project. Complete following steps:
To run the project dbt, you should be in the project folder:
cd dbt_glue_s3_tables
Run the dbt command:
dbt run --profiles-dir ~/.dbt/ --full-refresh
This command starts an AWS Glue interactive session, compiles the dbt models, and materializes all five tables (stg_customers, stg_orders, dim_customers, fact_orders, and fact_order_history) in your S3 Tables namespace. The --full-refresh flag rebuilds the incremental models from scratch, so it’s the right choice for the first run.
Query using Amazon Athena
Before testing the incremental merge and append behavior in the next section, confirm what the initial --full-refresh run loaded into the mart tables. Query the target tables.
In the Athena console, choose the data source and database that correspond to your S3 Tables catalog:
Run the following query to view the data loaded into the fact_orders table:
SELECT * FROM dbt_glue_s3_tables.fact_orders ORDER BY order_id;
The result returns the five order records:
#    order_id    customer_id    order_date    order_year    order_month    status    total_amount    customer_segment    segment_priority    dbt_updated_at
1    1001    1    2024-06-01    2024    6    completed    150.00    Premium    1    2026-10-16 09:41:46.590373 UTC
2    1002    2    2024-06-02    2024    6    completed    75.50    Standard    3    2026-10-16 09:41:46.590373 UTC
3    1003    1    2024-06-03    2024    6    completed    200.00    Premium    1    2026-10-16 09:41:46.590373 UTC
4    1004    3    2024-06-04    2024    6    unknown    125.75    Premium    1    2026-10-16 09:41:46.590373 UTC
5    1005    4    2024-06-05    2024    6    completed    89.99    Standard    3    2026-10-16 09:41:46.590373 UTC
Run the following query to view the data loaded into the fact_order_history table:
SELECT * FROM dbt_glue_s3_tables.fact_order_history ORDER BY updated_at;
The result returns the five order history records.
#    order_id    customer_id    status    order_date    total_amount    updated_at    recorded_at    event_year    event_month
1    1001    1    completed    2024-06-01    150.00    2024-06-01 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
2    1002    2    completed    2024-06-02    75.50    2024-06-02 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
3    1003    1    completed    2024-06-03    200.00    2024-06-03 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
4    1004    3    unknown    2024-06-04    125.75    2024-06-04 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
5    1005    4    completed    2024-06-05    89.99    2024-06-05 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
Incremental merge and append on Iceberg table
After the initial --full-refresh run succeeds, verify that the merge and append incremental strategies behave as expected when the source data changes. This demonstrates the row-level update capability that Iceberg on S3 Tables provides.
Update the sample source data
To simulate a real-world scenario where upstream source data changes over time (for example, a customer updating their profile, or new customers signing up), modify customers.csv to include both an update to an existing record and a new record.
order_id=1004: status updated from pending to completed with a later updated_at (to test the merge UPDATE).
order_id=1006: new record added with a later updated_at, associated with the new customer customer_id=6 (to test both the merge INSERT in fact_orders and the append in fact_order_history).
By running without --full-refresh, dbt runs its normal incremental logic instead of rebuilding the tables from scratch. In the staging layer, stg_customers and stg_orders apply the changes with a MERGE INTO statement that updates customer_id=1 and order_id=1004 in place and inserts customer_id=6 and order_id=1006. Downstream, fact_orders (merge) reflects the 1004 update and the 1006 insert as the latest state, while fact_order_history (append) records both 1004 and 1006 as new history rows.
Verify the results in Amazon Athena
After the re-run completes, use Athena to confirm that the merge and append strategies behaved as expected.
Run the following query to view the updated data in the fact_orders table:
SELECT * FROM dbt_glue_s3_tables.fact_orders ORDER BY order_id;
fact_orders returns 6 rows (one per order), with 1004 now completed and 1006 added.
#    order_id    customer_id    order_date    order_year    order_month    status    total_amount    customer_segment    segment_priority    dbt_updated_at
1    1001    1    2024-06-01    2024    6    completed    150.00    Premium    1    2026-10-16 10:06:55.944983 UTC
2    1002    2    2024-06-02    2024    6    completed    75.50    Standard    3    2026-10-16 10:06:55.944983 UTC
3    1003    1    2024-06-03    2024    6    completed    200.00    Premium    1    2026-10-16 10:06:55.944983 UTC
4    1004    3    2024-06-04    2024    6    completed    125.75    Premium    1    2026-10-16 10:06:55.944983 UTC
5    1005    4    2024-06-05    2024    6    completed    89.99    Standard    3    2026-10-16 10:06:55.944983 UTC
6    1006    6    2024-07-02    2024    7    completed    45.00    Premium    1    2026-10-16 10:06:55.944983 UTC
Run the following query to view the updated data in the fact_order_history table:
SELECT * FROM dbt_glue_s3_tables.fact_order_history ORDER BY updated_at;
fact_order_history grows from 5 rows to 7 rows on the second run (the 2 rows whose updated_at advanced: 1004 and 1006). Order 1004 now has two history rows: the original unknown status and the new completed status.
#    order_id    customer_id    status    order_date    total_amount    updated_at    recorded_at    event_year    event_month
1    1001    1    completed    2024-06-01    150.00    2024-06-01 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
2    1002    2    completed    2024-06-02    75.50    2024-06-02 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
3    1003    1    completed    2024-06-03    200.00    2024-06-03 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
4    1004    3    unknown    2024-06-04    125.75    2024-06-04 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
5    1005    4    completed    2024-06-05    89.99    2024-06-05 10:00:00.000000 UTC    2026-10-16 09:41:22.801835 UTC    2024    6
6    1004    3    completed    2024-06-04    125.75    2024-06-11 09:30:00.000000 UTC    2026-10-16 10:06:35.291993 UTC    2024    6
7    1006    6    completed    2024-07-02    45.00    2024-07-02 10:00:00.000000 UTC    2026-10-16 10:06:35.291993 UTC    2024    7
Clean up
To avoid ongoing charges, clean up the resources you created during this walkthrough. Complete these steps in the specified order to facilitate proper resource deletion.
Drop the tables dbt created in the S3 Tables namespace.
Delete the data this walkthrough wrote to your S3 bucket: the dbt warehouse data under s3://<YOUR-REGULAR-BUCKET>/glue/data/ and the sample CSV files under s3://<YOUR-REGULAR-BUCKET>/raw/. Leave the bucket itself in place if you use it for other workloads.
(Optional) Remove the local dbt project directory (dbt_glue_s3_tables) and the sample customers.csv / orders.csv files.
Conclusion
In this post, we showed how to build an end-to-end dbt transformation pipeline on Amazon S3 Tables with AWS Glue 6.0, using a staging and mart architecture. At the core of this pipeline are incremental models on S3 Tables, which let us transform and maintain data incrementally with SQL. We demonstrated two incremental strategies working together: the merge strategy to keep the latest state per order in fact_orders, and the append strategy to build an audit-friendly change history in fact_order_history.
S3 Tables support in the dbt-glue adapter is currently experimental (as of version 1.12.4) and will continue to evolve in upcoming releases. As with any experimental feature, we recommend thoroughly testing it in your own environment before use.
The BPF verifier has historically worked by tracing every possible path of
execution through a program, checking, at each instruction, that various safety
properties hold. This works, but it can result in an exponential increase in the
number of states that need checking in programs with complicated control-flow.
Alexei Starovoitov, one of the kernel’s core BPF maintainers, has shared
a patch set that substantially reworks how the verifier tracks states, in
order to reduce the size of that exponential explosion.
The PostgreSQL Global Development Group has announced
the release of PostgreSQL 19. Notable features in this release include the
introduction of the REPACK (CONCURRENTLY) command to optimize tables
without disruption to ongoing operations, better control over plan stability and
query performance with the new pg_plan_advice extension, and a number
of performance improvements.
In September, LWN covered the
removal of several features initially slated for this release. See the release notes for
a full list of new features and changes.
When an MDR provider contains a compromised endpoint, your team needs to know whether the weakness that enabled the attack exists elsewhere and who is responsible for addressing it. Without that follow-through, the immediate incident may be resolved while another attacker still has a way in.
Preemptive managed detection and response (MDR) is Rapid7’s approach to connecting exposure context, threat intelligence, AI-assisted investigation, and human expertise. It supports proactive cybersecurity by helping teams prioritize weaknesses before exploitation, investigate threats with a clearer understanding of risk, and use their findings to strengthen defenses.
How does preemptive MDR differ from traditional MDR?
Managed detection and response provides security specialists who monitor, investigate, and respond to threats around the clock. Many services also include proactive threat hunting and recommendations to improve security.
Preemptive MDR connects that work more directly to what makes an organization vulnerable. When analysts investigate suspicious activity on a server, knowing that it is internet-facing, supports a critical application, and has a vulnerability under active exploitation helps them assess urgency and determine where to look next.
In Rapid7’s model, exposure findings inform investigation and remediation priorities, while investigations reveal weaknesses that need attention. Security leaders gain a clearer connection between the threats their provider handles and the conditions their organization needs to address.
Within a broader preemptive cybersecurity strategy, MDR connects exposure information with the people investigating and responding to threats. The aim is to reduce opportunities for compromise and intervene before an attack causes harm, while retaining the expertise to contain and recover from incidents.
How exposure context and proactive threat hunting inform MDR
By combining information about assets, vulnerabilities, business criticality, and attacker behavior, preemptive MDR helps teams decide which weaknesses require action first. Exposure context also informs targeted hunting and the investigation of suspicious activity.
Consider a hypothetical organization running an internet-facing application affected by a newly disclosed vulnerability. The security team needs to establish whether the vulnerable software is present, what the application supports, and whether attackers are exploiting the weakness.
Those findings can guide remediation priorities and targeted hunting for signs of compromise. If suspicious activity appears, analysts investigate it with an understanding of the affected system and the potential route an attacker could take through the environment.
Depending on the evidence, the response may involve containing a system, examining related accounts, or expanding the investigation to other assets. The organization’s remediation teams also need clear recommendations about the underlying exposure.
What the investigation reveals then feeds back into detection rules, hunting priorities, and response procedures. This gives leaders a way to track an identified risk through investigation, action, and outstanding work, with clearer ownership at each stage.
What role does AI play in preemptive MDR?
Before analysts can assess a potential threat, they often need to retrieve logs, examine user activity, and connect evidence across several systems. AI can accelerate this work by gathering and correlating information for review.
Agentic investigation capabilities can perform elements of that process in parallel, test possible explanations, and organize findings. Their usefulness depends on the available data: missing identity activity or asset information can leave gaps in the account of what happened.
Rapid7’s approach keeps human expertise central to validation and response decisions. Analysts assess the evidence alongside the organization’s priorities and the consequences of an action, including whether isolating a system could interrupt a critical service.
What to look for in a preemptive MDR provider
When evaluating a service described as preemptive, ask the provider to show how exposure information changes its work. A redacted investigation should make clear what analysts knew about the affected asset, how that influenced their reasoning, and which actions followed.If an investigation identified a weakness, was it assigned to an owner and addressed? Did the findings change detection coverage or future priorities? Where AI contributed, the provider should explain its role and the oversight applied.
Incident response remains part of the requirement. Rapid7 MDR includes unlimited incident response alongside exposure-informed defense and AI-assisted investigation, supporting containment, detailed analysis, and threat eradication.
Agree on responsibilities before that support is needed. Establish which actions the provider can take, when customer approval is required, and who owns remediation. Those arrangements determine how findings become action, particularly when taking a system offline carries business consequences.
Once the service is operating, review progress through specific cases: exposures addressed before exploitation, threats contained, and weaknesses closed after investigation. Ask to see the evidence behind those outcomes and any work still outstanding, so your team can judge where risk has changed and where further attention is needed.
Explore Rapid7 MDR to see how exposure-informed defense, AI-assisted investigation, and expert response work together.
For a threat actor, the perfect malware is one they don’t have to write, and already does all they need. One example of this is shown by the China-aligned APT known as Webworm, which has been known to deploy the open-source SoftEther VPN into the networks of compromised governmental organizations to maintain low-profile, long-term access.
After this was publicly documented and defenders could keep an eye out for this tactic, the actor presumably started thinking of ways to make their covert access stealthier. In this post, we share our analysis of what we believe to be a so-far unknown custom SoftEther-based tool, which implements various tricks to hide itself from security tools, and which we attribute to Webworm with moderate confidence. We additionally provide guidance and tooling for detecting its presence on a system and extracting the configuration(s) associated with it.
Technical analysis
To illustrate how the tool works, we will use the only public sample of this tool we are aware of, which can be found in our IoCs list (90e7…).
The sample is a Windows PE32+ file targeting the x64 architecture. Based on cleartext strings and constants in the binary, we identified it as a (modified) build of the SoftEther VPN Bridge executable, specifically version 4.44, build 9807. Similarly, the PDB path included in the executable reads C:\Users\Administrator\Desktop\SoftEtherVPN_Stable\SoftEtherVPN_Stable\SoftEtherVPN_Stable\src\DebugFiles\pdb\x64_Release\vpnbridge.pdb. As such, the tool doesn’t hide its identity from reverse engineers, only external interactions.
The first and most trivial change the threat actor implements is in the PE metadata. Here we learn that the OriginalFileName of this binary is netcapa.exe, and it brands itself as “Network Monitor Software” published by a company named “Network Systems Solutions Inc.“. The only field unchanged against the stock SoftEther executable (vpnbridge_x64.exe) is the Version, which reads 4, 44, 0, 9807.
Next, we wanted to identify any functionality added or modified by the threat actor. The SoftEther bridge alone is a powerful tool to maintain remote access to a compromised network, but we wanted to know if perhaps there was a backdoor to give the threat actor direct command execution on the infected host. For that reason we checked out the corresponding tag in the public “SoftEtherVPN_Stable” repository on GitHub and compared it to the decompiled sample.
Internal rebranding
The rebranding apparent in the exposed metadata extends into internal strings used in debug banners, service names, registry keys, the contents of the server’s HTTP 401 error page, or firewall rule names, where occurrences of “SoftEther VPN” are replaced by “NtMonitor VPN”.
However, the renaming is inconsistent; for example, the service name used by the entry point is still SEVPNBRIDGE, and many registry key paths still reference the “SoftEther Project”.
Network stealth
Stock SoftEther VPN Mayaqua/Network.h defines HTTP endpoints used by the protocol:
A client initiating a connection to a SoftEther VPN server will send a handshake request to HTTP_VPN_TARGET2 along with a “watermark”, i.e. a byte pattern proving that the client is speaking the correct VPN protocol. Otherwise, the server answers with a decoy HTTP response.
NtMonitor changes the upstream GIF watermark with a custom byte pattern (a truncated PNG file showing the Windows logo), so that stock SoftEther clients and servers cannot handshake with this build, and NtMonitor’s own peers cannot be fingerprinted with the well-known stock GIF watermark.
Embedded resource archive
As the threat actor probably realizes, a SoftEther resource archive named hamcore.se2, which sits next to the executables in the installation directory and is required to be present at runtime, provides a straightforward detection opportunity for unauthorized installations. We think that, for this exact reason, the actor chose to reduce the contents of this archive to a bare minimum, package the archive inside the bridge executable itself (as a PE resource), and implement a custom resource directory walk to load the archive at runtime. As a side effect, this increases the binary’s size by about 1.5 MB compared to the official build.
Encrypted configuration
Another weak point (for the attacker) in stock SoftEther is that its configuration is stored on disk in plain text in a well-recognizable format. The actor changes its name from vpn_bridge.config to setting.conf and modifies the configuration loader to handle custom-encrypted files that start with the magic bytes RCEN in ASCII. The rest of the encrypted file has a simple format and includes the encryption key. A Python script to decrypt such files with the actor’s custom RC4-like cipher is available on the Rapid7 Intelligence GitHub repository.
Attribution and interpretation of findings
Beyond the changes described above, we did not identify any additional malware functionality. Clearly, the threat actor prioritizes stealth above raw capability. It seems like they methodically analyzed SoftEther’s detection surface and implemented counter-measures to all of the easy ways a detection engineer may target it. At the time of our analysis, only one anti-virus vendor detected the sample on VirusTotal, although it has been public since January.
This aligns well with the TTPs previously reported for Webworm by ESET, and such attribution is further supported by indicators in decrypted configurations Rapid7 Intelligence has access to. In all of the cases, the VPN is configured to bridge (“cascade”) a remote network into the local one; furthermore, in cases that were not likely deliberate tests, the remote IP address was located inside AS 20473 belonging to The Constant Company, LLC, which (also including its subsidiary, Vultr) has been associated with Webworm on many occasions in the past.
Considering this attribution, we can put together some important takeaways: Quite likely, we are looking at a new evolution in the tooling used by Webworm, a China-aligned APT whose activity is known to focus on governmental organizations, especially in Europe. Earlier this year, ESET already noted this group to shift away from custom malware to dual-use tools such as SoftEther VPN, but now we are observing a sort of hybrid of the two — stock SoftEther software that is not trojanized, but rebuilt from source in a way that erases much of its detection fingerprint.
Detection guidance
To detect this particular variant of Webworm’s tooling, we provide a list of IoCs and a YARA ruleset on our public GitHub repository. If you have the ability to inspect TLS traffic in your organization, one of the most reliable detections you can deploy right now is to look for POST requests to /update/picture.cgi with Content-Type: image/jpeg and a request body starting with and 89 50 4e 47 0d 0a 1a 0a 00 00 00 0d 49 48 44 52 (initial bytes of the custom PNG watermark).
Although the samples we have seen all use the same NtMonitor branding internally (despite the PE metadata differing across samples), this is the easiest change for the threat actor to implement next. Similarly, the HTTP endpoints and watermark can be swapped out trivially. As such, we recommend defenders in the government sector to familiarize themselves with intrinsic SoftEther VPN behavior in order to stay one step ahead of when the threat actor decides to update the tool next.
MITRE ATT&CK techniques
Technique ID
Technique Name
Comment
T1587.001
Develop Capabilities: Malware
The actor is maintaining their own fork of SoftEther VPN used for malicious purposes.
T1027.013
Obfuscated Files or Information: Encrypted/Encoded File
Configuration files are encrypted with a custom cipher.
T1140
Deobfuscate/Decode Files or Information
Encrypted configuration files are decrypted at startup by the modified loader.
T1036.005
Masquerading: Match Legitimate Resource Name or Location
PE metadata is purposefully changed to masquerade as a generic system service.
T1027.005
Obfuscated Files or Information: Indicator Removal from Tools
Known SoftEther artifacts are systematically removed from the binary.
T1686.003
Disable or Modify System Firewall: Windows Host Firewall
Using stock SoftEther functionality, the malware adds rules to the system firewall.
T1599
Network Boundary Bridging
The VPN bridge binds together the infected host’s local area network with the attacker’s.
T1071
Application Layer Protocol
C2 communication uses HTTP(S) and SoftEther’s application protocol.
T1090.001
Proxy: Internal Proxy
The infected host serves as an internal proxy mediating C2 access to other hosts on the network.
Version 8.6.0 of
PHP has been released. Notable changes in this release include a polling API, a
new clamp() function, a SortDirection enum, and a \Time\Duration class. See “What’s new in 8.6”
for more on new features, and the changelog for a full list
of changes.
The PHP Project has announced the release of PHP 8.5.13, 8.4.28, 8.3.37, and 8.2.36. Each contains a
number of security and bug fixes, including several fixes for critical
vulnerabilities that could allow remote-code execution. According to the
project’s pre-release
announcement on November 18, all of the vulnerabilities of critical
severity “require either non-default configuration or uncommon
setups“. See the release notes for details; Linux vendors and projects
should be releasing updated packages soon.
Visitors to government election websites surged 363% on November 3, the date of the 2026 midterm elections in the United States. Across Cloudflare's election protection programs, we also detected a significant shift in the types and timing of cyberattacks throughout 2026.
Unlike what we saw in other recent elections, attackers focused on gaining access to internal systems and data, rather than knocking websites offline. Government election websites faced website vulnerability attempts 180 times more often than denial-of-service (DDoS) attacks, and at roughly ten times the rate of Cloudflare's broader customer base. We also found evidence of at least one attempt to exploit a recently disclosed critical PHP vulnerability on a state government voting website in the Western United States.
These attacks peaked in late October, several weeks before the election. Vulnerability exploit attempts climbed steadily throughout 2026: from 200,000 per day in January, to 2 million per day in October. However, on Election Day in the U.S., Cloudflare detected no escalation in attack volume and zero major DDoS incidents across protected election sites, marking a sharp contrast to other recent elections, such as in Moldova last year.
Our data regarding cyberattacks on election institutions came from organizations participating in Cloudflare's free cybersecurity programs: the Athenian Project, Cloudflare for Campaigns, and Project Galileo. Together, these initiatives helped protect more than 1,400 election-related websites during the 2026 U.S. midterm elections, including those belonging to state and local governments, candidates, political parties, voting-rights advocates, journalists, and civil society groups.
Cloudflare launched its first election protection program in 2016 after widespread reports of cyberattacks targeting the U.S. elections. A decade later, it is remarkable to see how far governments and campaigns have come in securing their digital infrastructure. We are proud to help protect democratic institutions and are encouraged that cyberattacks were once again not a disruptive factor in 2026.
In this post, we examine traffic and attacks observed against those organizations on Election Day, analyze the most common types of attacks of the 2026 cycle, and provide recommendations based on those findings.
Ordinary user traffic to state and local government election websites was higher on Election Day (November 3) than any other day in 2026. Traffic to those sites increased to approximately 602 million requests, up from 130 million on November 1. By comparison, traffic across the rest of Cloudflare’s global network rose by only 12% over the same period.
State and local government election websites provide authoritative information to voters on how to register, where to vote, and who won. Because of their critical role, these platforms are often targeted by those seeking to suppress voter turnout, disrupt the reporting of results, or steal sensitive information.
On Election Day itself, Cloudflare did not record a single significant distributed denial-of-service (DDoS) attack across any of its 1,400 election-related websites. The only significant DDoS attack occurred on November 2, targeting a candidate for the U.S. House of Representatives in California and totaled 520,000 requests. By comparison, the Moldovan Election Commission experienced more than 898 million malicious requests in a single 12-hour period on their Election Day in 2025, with attacks peaking at 324,333 requests per second.
Prior to Election Day: the most common attacks in the 2026 cycle
Website vulnerability scans were by far the most common attack observed by Cloudflare in the 2026 U.S. election cycle. In the 12 months leading up to the election, Cloudflare mitigated 392 million such attacks on government election websites alone.
Website vulnerability attacks exploit outdated or vulnerable website code to gain access to internal systems and data. For example, cross-site scripting attacks inject malicious code into web pages in order to capture administrator credentials or deface site content. SQL injection manipulates database queries allowing attackers to potentially extract voter records or alter data.
Phishing and other malicious emails targeting political campaigns protected by the company occurred at rates consistent with Cloudflare's broader network, but showed signs of sophistication. In the 90 days leading up to the election, 3.9% of emails sent to organizations participating in Cloudflare for Campaigns were identified as malicious, closely tracking the 4.8 percent baseline across other Cloudflare customers. However, nearly 42% of those malicious emails managed to bypass basic email authentication checks, such as verifying sender identity or preventing in-transit tampering. These threats were nonetheless identified by Cloudflare’s advanced phishing detection tools.
Although website vulnerabilities were the most common attack overall, for journalism and election-related civil society organizations, DDoS was the most common. Over the same 12-month period, Cloudflare mitigated over 10.8 billion DDoS requests targeting these groups. The largest single attack occurred on September 10, 2026, hitting a U.S.-based news organization with 3.04 billion requests. This pattern is consistent with Cloudflare research released earlier this year, which found that among all Project Galileo entities in 120 countries, DDoS were by far the most common attack seen, accounting for 81% of all attacks.
PHP vulnerability
On October 21, security researchers disclosed serious vulnerabilities (known as php2shell) in PHP, an open source back-end programming language used by 70% of the world's websites. The flaws reportedly could allow attackers to execute malicious code on vulnerable servers, expose customer data, or disrupt services. Cloudflare deployed Web Application Firewall (WAF) protections for all customers, prior to public disclosure of the vulnerability.
On October 22, Cloudflare's PHP defense was triggered more than 9,000 times on a state government election website in the Western U.S. This attack was only detected on one election-related site and appears to have been an isolated incident rather than part of a broader trend.
Recommendations
Cloudflare research consistently shows that individuals and organizations participating in democratic elections face significant risk of cyberattack. Data gathered during the 2026 U.S. midterm election suggests those attacks continue to evolve, occur throughout an election cycle and not only on Election Day, and can vary depending on the type of organization targeted.
Based on the recent cyberattack trends in the 2026 U.S. midterms and other elections, we make the following recommendations:
Prepare for surges in user traffic. Legitimate voter interest can create traffic spikes that overwhelm unprepared infrastructure and make essential election websites inaccessible. Organizations should prepare scalable, efficient infrastructure to handle Election Day traffic increases without straining budgets or staff.
Maintain security protections year-round, not just on Election Day. Cyberattacks targeting democratic institutions occur across the entire election cycle, not just around voting windows. Defensive postures must remain active continuously rather than treated as a short-term, seasonal measure.
Deploy automated defenses to counter rapid threats. AI has made it easier for attackers to find and exploit new vulnerabilities. Organizations should implement security services that update automatically, like managed rules, to ensure new protections deploy by default.
Ensuring voters have access to reliable information about elections not only helps encourage participation and deliver timely, accurate results, but also protects voter confidence in the democratic process itself. As more officials, more institutions, and the public increasingly rely on the Internet for those services, keeping that digital infrastructure stable, secure, and accessible becomes an essential civic priority.
State and local election offices, political campaigns, party organizations, journalists, and voting rights groups in need of cybersecurity services can access them from Cloudflare at no cost. Visit the Athenian Project (for state and local election websites), Cloudflare for Campaigns (for political campaigns), or Project Galileo (for civil society, democracy, and journalism organizations) to learn more about eligibility and sign up today.
Ясно помня първите си две дела. Помня ги с тялото повече, отколкото с паметта. Лекото гадене, сухата уста, усещането, че температурата ми се вдига с половин градус на всеки етаж. Пиех вода, мачках пластмасовата бутилка, беше горещо и задушно. Вътре никой не пушеше. На всеки етаж имаше балкони и там, между саксии с изсъхнали мушката, в общ облак димяха адвокати, призовкари и подсъдими – демократично и с липсващо процесуално разделение на ролите.
Въпросът, който ме глождеше, беше простичък и неприятен:
Имам ли подготовката, а и правото да правя това?
Бях чел, естествено. Бях минал онлайн обучението, бях решавал тестове и получих отлични резултати, което ме успокои приблизително колкото шофьорската книжка успокоява съвестен човек, който за първи път излиза на магистрала. Бях се оправил и с електронния подпис, с който получавам достъп до материалите и с който по-късно подписвах делата. Официално обаче още не бях заклет. Законът изисква съдебните заседатели да положат клетва пред общото събрание на съдиите, но заради ковид протоколите тържествеността беше отложена и влизах в съдебната власт някак странично, през служебния вход на процедурата. Обучението ме беше въвело в етичните правила, записани в наредбата за съдебните заседатели, сред които са
безпристрастност, дискретност, задължение за отвод при най-малкото съмнение за личен интерес.
Звучеше като устав на средновековен орден, преведен на езика на държавната администрация. Носех го в главата си, сякаш беше наръчник, който предстои да изпробвам на терен.
Сградата живееше свой собствен живот. Служители бутаха огромни колички, натоварени с папки като пощальони от деветнайсети век. Вратите се отваряха с пропуски, които никога не сработваха от първия път. Обикалях гишета, питах, получавах отговор, който пораждаше нов въпрос, и през цялото време ме съпровождаше кафкианското подозрение, че съм в грешна стая, объркал етажа, часа и деня. Кафка, юрист по образование и чиновник в застрахователен институт, е знаел добре, че
ужасът на закона живее най-вече в коридорите и пред вратите.
Първото ми заседание беше за дело със 17-ти състав, при съдия Петров. Залата не беше обявена предварително и се оказа №21. Чаках, вълнувах се и същевременно ме обземаше онази скука, която придружава всяко чакане, независимо от залога. До мен седяха две възрастни жени, дошли за друго дело, разговаряха за цените на доматите и за внуците си, което някак ме успокои, всичко беше нормално, животът продължаваше да си тече тихо и познато. Другата съдебна заседателка се казваше Мария Георгиева, работеше в отдел „Човешки ресурси“ на голяма банка и се занимаваше с трудово право, а мъжът ѝ от двайсет и пет години беше адвокат по наказателни дела. Тя имаше спокойствието на човек, слушал юридически истории всяка вечер от поне четвърт век. Съдията закъсня с двайсет минути.
Подсъдимият беше бездомен човек, бивш огняр, вписан като управител на фирма за търговия на едро със захар и олио, която не беше платила данък добавена стойност за над 7 милиона лева.
Подставено лице, сламен човек, както казват юристите, на хартия собственик на империя, която никога не беше виждал. Обвинението беше по член 255 от Наказателния кодекс за избягване на данъчни задължения в особено големи размери. Седеше със старото си яке, гледаше пода и вероятно не би могъл да обясни какво е ДДС.
Хана Аренд, германско-американска философка, говори за баналността на злото в съвсем различен мащаб. Атмосферата беше подобна на онази в залата с крехкия и тъжен човек, натоварен с огромната сума. Прокурорът прочете обвинителния акт с равен, леко уморен глас, в който числата звучаха абстрактно. Служебният защитник, млад и съсредоточен, подреждаше листовете си с педантичността на шахматист. Съдията обясни на подсъдимия правата му бавно, изречение по изречение, с търпението на начален учител и го попита дали е разбрал. Той кимна. В бележника си записах първото си впечатление, три думи, които по-късно зачеркнах, защото присъдата се ражда от доказателствата и от времето.
Делото започна с онова, което наричам юридически катехизис. Покажете лични карти. Имена, дата на раждане, адрес. Към свидетелите и вещите лица винаги ехти „Дела и родства със страните имате ли?“ – въпрос с почти библейска интонация, който след десетото повторение звучи като литания. Предупреждение за наказателната отговорност при лъжесвидетелстване. Подпис. Ритуалът има своя смисъл, разбира се, той удостоверява, че всички в залата са тези, за които се представят, и знаят какво се случва. Театралният човек в мен веднага забеляза мизансцена, издигнатата маса на състава, прокурора от едната страна, защитата от другата, свидетеля в центъра, с гръб към публиката като в античната орхестра.
След заседанието трябваше да отида в информационното обслужване за още една подробност за електронния подпис, после да се върна в деловодството и да кажа какво става с делото, дава ли му се ход и кога е следващото заседание. Отговорността да следиш се оказва изцяло твоя, т.е. моя. Някой ден през седмицата трябваше да занеса и напечатана банкова сметка за възнаграждението и в стая 112 ме чакаха материалите от обучението.
Правосъдието, научих бързо, се състои от големи принципи и безкрайно много малки хартийки.
Второто заседание в същия ден беше за по-дребно и тъжно престъпление. Кражба на телефон и 30 лева от две момчета от „Надежда“, по член 194. Малка зала, съдийката закъсня, другият съдебен заседател, възрастен господин с вратовръзка, ми прошепна, че съучастничката на единия подсъдим много прилича на негова бивша колежка от завода. Не беше тя. Бързо ми стана ясно колко лесно личното се вмъква в правосъдието и колко важно е заседателите да идват от различни светове. Момчетата дойдоха като свидетели заедно с майките си, облечени официално като за абитуриентски бал и разказваха с точността на хора, преповтаряли историята пред приятели десетки пъти. Трийсетте лева имаха в залата същата процесуална тежест като седемте милиона от сутринта. Ритуалът беше същият, катехизисът също, лични карти, дела и родства, подпис. В това равенство пред процедурата има нещо дълбоко демократично и леко абсурдно, което Чехов би оценил.
Още след тези две дела разбрах няколко неща, които противоречаха на представите ми. Съдебната система функционира доста по-ефективно, отколкото предполагах. Има срокове и те се спазват, ясно е кой какво върши и защо. Делата се разпределят на случаен принцип чрез електронната система на съдилищата, същата логика определя и кои заседатели ще седнат в състава. Тази лотарийна справедливост, която древните атиняни са ценели при избора на своите съдии, ми се стори едновременно модерна и стара колкото самата демокрация. Видях колко широки са правомощията на съдията в залата и колко голяма власт има прокуратурата. Тя решава кое дело изобщо ще се добере до съда и в какъв вид, стига да реши да използва силата си отговорно и адекватно. Разбрах и нещо по-обезпокоително.
Средностатистическият съдебен заседател често е бивш служител на МВР, на съдебната система или роднина на такъв.
Така институцията, замислена като глас на обществото, рискува да се превърне в ехо, рима и копие на самата система. Нилс Кристи сигурно би се намръщил и би написал петиция.
Кристи, норвежки криминолог, в есето си „Конфликтите като собственост“ от 1977 г. описва модерния съд като място, където конфликтът се отнема от хората, на които принадлежи. Пострадалият се превръща в свидетел по собственото си дело, извършителят – в обект на процедура, а общността наблюдава отстрани. Предложението му е съд, ориентиран към пострадалия и към квартала, с участието на непрофесионалисти, където страните се срещат лице в лице и говорят за щетата, причините, възможната поправка и едва след това за наказанието. Тази идея се превръща в една от основите на възстановителното правосъдие, развито по-късно от Хауърд Зер, американски криминолог, и приложено в практики като медиацията между пострадал и извършител, семейните конференции в Нова Зеландия, вдъхновени от традициите на маорите, и възстановителните кръгове в Канада.
Смисълът е прост и дълбок: престъплението наранява конкретни хора и отношения и правосъдието има задачата да ги възстанови, доколкото е възможно. Изследванията в редица страни показват по-висока удовлетвореност сред пострадалите и по-малко рецидиви сред извършителите, участвали в такива срещи. В България подобни практики живеят предимно в пилотни проекти и в работата с непълнолетни. Съдебните заседатели обаче са готов мост към тях. Те са хора от квартала, носители на житейски опит и здрав разум, които могат да внесат в съда въпросите на Кристи за това кой е пострадал и как може да се поправи вредата. Двете момчета от „Надежда“ и майките им заслужаваха и такъв въпрос.
Успокоявах се постепенно и бавно след този първи ден – кортизол и адреналин се бяха смесили във висока доза. Никога няма да забравя специфичната лекота, която изпитах тогава и изпитвам всеки следващ път, щом напусна съда и изляза на въздух. Никой не ме преследва, не ме отвежда с белезници, правата ми не са ограничени. Мога да пътувам, да спра да послушам уличните музиканти, да отида на работа в Театрална работилница „Сфумато“, да продължа кореспонденцията за гостуване в Румъния, да вляза в онлайн среща на борда на директорите на Съюза на театрите на Европа, да преговарям за авторските права на Бекет и на Дънкан Макмилан. И да очаквам с нетърпение да стана баща. Свободата, оказва се, се усеща най-ясно на изхода на съда. В следващия текст ще разкажа за различните и най-чести дела, с които се срещнах отблизо, и за хората, които излизаха през същата врата, без да усетят лекота.
(Следва продължение.)
С оглед на тайната на съвещанието и защитата на личните данни всички имена, номера на състави и зали, суми, предмети на делата и обстоятелства по тях са променени. Всяка прилика с действителни лица и дела е случайна.
превод от английски Владимир Молев, София: изд. „Колибри“, 2016, 2025
Гостуването на един от най-емблематичните съвременни писатели – австралиеца Ричард Фланаган, съвпадна с премиерата на току-що издадената му у нас квазимемоарна книга „Въпрос 7“, както и с ексклузивната прожекция (в рамките на кинофестивала „Синелибри“) на първия епизод от минисериала „Тесният път към далечния север“. Именно за едноименния адаптиран роман на автора, удостоен през 2014 г. с наградата „Букър“, ми се иска заслужено да припомня тук. Той излезе у нас през 2016 г. в превод на Владимир Молев, а миналата година се появи във второ, обновено издание с нова корица.
Имах щастието да взема интервю от Фланаган преди срещата му с българските читатели. Разговарях с един уморен от огромната часова разлика човек, наясно със своята популярност, подготвен да говори при всякакви обстоятелства и с отработен автоматизъм по няколкото стандартно извеждани теми, отразяващи най-вече любопитството на читателите към неговата непозната и далечна родна Тасмания. Бързо стана ясно обаче, че за трийсетте минути (след предвидените петнайсет) просто няма как да покрием, камо ли в дълбочина, всички дълбоки екзистенциално-философски въпроси, които четирите му издадени у нас книги повдигат. В този материал ще маркирам и някои от тези незададени питания.
Фланаган справедливо е отбелязвал, че всички негови романи в крайна сметка могат да се разглеждат като автобиографични. Действително цялото му творчество може да се разглежда като един метатекст, в който прототипи, мотиви и сюжети мигрират. „Въпрос 7“ обобщава по биографично-мемоарен начин големите събития и теми, които писателят фикционализира толкова успешно от дебютната си книга „Смъртта на речния водач“ насам (базирана на давенето му в река Франклин, когато буквално е върнат от смъртта). Всичко това е свързано и с осъзнаването, че писането неизбежно е отражение на собствените ни формални, психически и аналитични опитности, и най-вече с идеята за паметта като форма на въображение, като творчески жест към миналото, което тя възстановява, запълва и подрежда така, както един писател гради сюжетите си.
Сред тези големи теми, които сякаш не просто занимават, а истински обсебват автора, са и преживяванията на баща му Арчи Фланаган като военнопленник през Втората световна война. Върху тях той построява своя букъров епос „Тесният път към далечния север“, но продължава да се връща и в редица нехудожествени текстове и статии, и във „Въпрос 7“. Докато за този последен роман Фланаган посещава лагера Охама в Япония, където баща му е бил подложен на принудителен труд във въглищна мина, и се връща към собствените си спомени за него, то в „Тесният път към далечния север“ той се пренася в годините преди това, към т.нар. линия на смъртта – железница, която австралийски и други военнопленници прокарват в джунглата между Сиам (Тайланд) и Бирма под контрола на японците.
И докато „Въпрос 7“ е фин ретроспективен опит за осмисляне и отдаване на почит към преживяното от бащата, но и любящ поглед към отраженията на този травматичен опит върху неговата личност и живот по време на израстването на самия Фланаган, то „Тесният път към далечния север“ не се пести и разгръща в зрелищна вакханалия случилото се на линията на смъртта, драматизира по смазващо графичен начин разказите за непосилните условия, (само)убийствената йерархия и нечовешкия принудителен труд, на който са подложени военнопленниците.
Нещо повече. Докато в мемоарната книга става ясно, че с времето Фланаган-старши е подложил паметта си за тези събития на опрощаваща редукция, пресявайки с годините спомена за злото до една съхраняваща, смиряваща и осмисляща идея за любовта, то в романа си Фланаган е заместил – и облекчил – баща си (прототипа на протагониста Дориго Еванс) в натуралистичното обговаряне на човешката жестокост, в невъзможността да избягаш от бремето на миналото.
Забравянето може да е форма на спасение или съпротива, но в „Тесният път към далечния север“ протагонистът е наказан с помнене.
И ако един друг роман на Фланаган, излязъл в началото на годината – „Живо море от сънища наяве“, може да се нарече роман за изчезването и своеобразна критика на егоистичната антропоцентрична индустрия на индивидуалното безсмъртие за сметка на колективното планетарно опустошение, то „Тесният път към далечният север“ е класическа поема за оцеляването. За неговата – много меко казано – неестетична прагматичност, за неговата живителна гнусота, за неговия „просветен егоизъм“, развенчаващ плакатните разбирания за алтруизма и героизма.
Именно този „просветен егоизъм“, както по-късно Фланаган го дефинира при един разговор с баща си, бива демонстриран чрез случващото се в „Тесният път към далечният север“ – насред душните и влажни гори на Сиам, калта и изпражненията, глада и безмилостните насекоми, болестите и гниенето на плътта и духа човешки. Осъзнаването, че единствено в спойка с другите, чрез отстъпки и жестове към тях увеличаваш шанса си сам да оцелееш, подрива саможертвената патетика и юначните жестове в името на един откровен и прагматичен кодекс на оцеляването.
Тази рецепта за съхранение, следвана от австралийските военнопленници (за разлика от японците, които мрат като мухи, макар те да са „господарите“ в тази история), е базирана на скъсването с йерархията. Едно от най-ясните осъзнавания в романа е, че традиционно възхваляваната желязна йерархия в японското общество, смятана за непоклатим гарант за ред, ефективност, стабилност и най-вече зачитане, всъщност е колос върху глинени крака. Абстрактната идеализация на горестоящия, чак до божествената неприкосновеност на императорската воля, се осъществява с цената на свръхчовешко усилие, вредно себеизличаване и разпадаща се човешка логика. Те много повече виктимизират и поставят под съмнение контрола и властта, отколкото там, където офицерите измежду военнопленниците споделят своите заплати с редовите войници, разпределят дажби и проявяват уж алтруизъм и милосърдие. Да се положиш за другия в името на себе си е изведено като парадоксалната формула на това оцеляване.
Чрез своите герои Фланаган ни представя различни защитни механизми за справяне с безсмислието на жестокостта и злото, издигнати почти до мистичен феномен, необясними до отвъдност. Ала завладяващото в тази история не е дори някакво дълбоко екзистенциално осмисляне на страданието, а простичкият, понякога до нелепа трагикомичност начин, по който събраните от кол и въже мъже го рационализират, понасят и абсорбират. Насред бруталността мъжеството се проявява дори в липсата на съпротива, в самото изтърпяване на безсмислието. Фланаган не е сантиментален дори когато е чувствителен, дори когато говори умилителния език на човечността. Грубоватата, посредствена и несъвършена човечност, понякога по-скоро дори случайна, насилена под напора на обстоятелствата, отколкото плод на съзнателно героично усилие.
На този фон е логично да се запитаме дали Фланаган не ни предлага една картина, която опровергава онзи известен израз на св. Августин. Защото не е ли всъщност именно доброто временна липса на зло – бърз, недостатъчен опит истината за първоначалието на злото в света да бъде скрита? Не успях да попитам Фланаган, но ми се струва, че не би се съгласил – нищо че в романа сам опровергава стойността на оцеляването. Резюмирайки случилото се с всеки от героите на романа след войната, той ни показва неокончателността на този процес, цената на оцеляването, спестеното на загиналите.
Посттравматичното стресово разстройство, официално въведено като термин през 80-те, е било непознато по онова време, но мнозина от мъжете очевидно страдат от него под една или друга форма през целия си живот. Оцеляването се превръща в ахронично хронично състояние. Изпражненията, въшките, холерата и боят в лагера съществуват сублимирани – паралелно с известността, интервютата и официалните коктейли в късните години на този успешен хирург, произведен в национален герой по силата на оцеляването си, по силата на това, че носи травмата да е жив.
Фланаган изобличава не автентичността на героизма, а кухото му провъзгласяване за такъв от ония, които не са понесли неговия провал.
Този дълбоко, но невидимо пропукан образ днес е емоционално вцепенен авторитет, провалил се съпруг, сериен прелюбодеец и парадоксално, единственото му опрощение е в отнетото му право на любов.
Ако има една линия, която атемпорално събира и надмогва всички останали времеви линии в романа, то това е невъзможната почти до имагинерност любов на Дориго Еванс към съпругата на чичо му. Любов, която едновременно боли и лекува, съшива и разнищва, противопоставя своя екстазен ад на мъчилището в джунглата. Подобно на нея, Фланаган още в името на романа противопоставя в жестока ирония възвишената поезия (заглавието е цитат от Башо) на институционализираното и идеологически идеализираното варварство. Метафората на красивото духовно търсене при Башо е буквализирана в прокарването на застлан с човешки трупове и изпражнения брод през джунглата.
Както във всяка добра литература, Фланаган дава и другата – японската – перспектива. Подходът, който ни показва крехкостта на човека и от двете страни, моралната относителност, дълбоките основания, е задължителен за високата проза. И все пак не ми даваше покой въпросът (до който също не стигнахме) дали можем да си позволим фразата „въпрос на гледна точка е“ във времена, когато сме изправени пред невъзможността, поне на ниво политици, недвусмислено, черно на бяло да посочим агресора в нашата съвременна война. Колко в дълбоко личното трябва да се пренесем, за да изпитаме еднаква емпатия към загубите и от едната, и от другата страна?
Повърхностна и неинтелигентна ли е категоричната морална оценка?
Поставяйки ги в контекст, Фланаган ни кара да изпитаме състрадание дори към най-свирепите поданици на японския император (действащи според кодекса бушидо), ала сам признава, че изкуплението и отмъщението не могат да възстановят справедливостта и равновесието. Той не успя да отговори на въпроса ми дали изобщо вярва в някакъв баланс, в някаква изначална, логична справедливост на съществуването?
„Тесният път към далечния север“ е роман за смъртта на духа след оцеляването на плътта. Едновременно брутален и лиричен, романът е словесен паметник на хилядите останали завинаги в калта на далечния север по пътя към една надмогваща човека идеология. Препоръчвам да прочетете тази своеобразна класика заедно с последния издаден у нас роман на Фланаган „Въпрос 7“, както и да обърнете внимание на „Живо море от сънища наяве“, който пък дава контрапункт от различен, болезнено актуален съвременен ъгъл (екологичен и климатичен) на целия смисъл на опростенчески героизираното в толкова много литературни произведения човешко оцеляване.
Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. За нея медията „Тоест“ е отличена с Националната награда „Христо Г. Данов“ (2025) за принос в представянето на българската книга.
Рубриката е част от партньорската програма Читателски клуб „Тоест“, благодарение на която активните дарители на „Тоест“ получават 20% отстъпка от коричната цена на всички книги на включените издателства. Изборът на заглавия обаче е единствено на авторите Стефан Иванов, Севда Семер и Антония Апостолова, които биха ви препоръчали тези книги и ако имаше как да се разходите с тях в книжарницата.
Front: C++26 standard; Buildroot; Faster futexes; Zellij; Julia language.
Briefs: Glasswing; NGINX RCE; XRAID; Manjaro nonprofit; 30 years of curl; MATE; Redict deprecated; Rust 1.100; Quotes; …
Announcements: Newsletters, conferences, security updates, patches, and more.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.