Enhanced search with match highlights and explanations in Amazon SageMaker

Post Syndicated from Ramesh H Singh original https://aws.amazon.com/blogs/big-data/enhanced-search-with-match-highlights-and-explanations-in-amazon-sagemaker/

Amazon SageMaker now enhances search results in Amazon SageMaker Unified Studio with additional context that improves transparency and interpretability. Users can see which metadata fields matched their query and understand why each result appears, increasing clarity and trust in data discovery. The capability introduces inline highlighting for matched terms and an explanation panel that details where and how each match occurred across metadata fields such as name, description, glossary, and schema. Enhanced search results reduces time spent evaluating irrelevant assets by presenting match evidence directly in search results. Users can quickly validate relevance without analyzing individual assets.

In this post, we demonstrate how to use enhanced search in Amazon SageMaker.

Search results with context

Text matches include keyword match, begins with, synonyms, and semantically related text. Enhanced search displays search result text matches in these locations:

  • Search result: Text matches in each search result’s name, description, and glossary terms are highlighted.
  • About this result panel: A new About this result panel is displayed to the right of the highlighted search result. The panel displays the text matches for the result item’s searchable content including name, description, glossary terms, metadata, business names, and table schema. The list of unique text match values is displayed at the top of the panel for quick reference.

Data catalogs contain thousands of datasets, models, and projects. Without transparency, users can’t tell why certain results appear or trust the ordering. Users need evidence for search relevance and understandability.

Enhanced search with match explanations improves catalog search in four key ways:
1) transparency is increased because users can see why a result appeared and gain trust,
2) efficiency improves since highlights and explanations reduce time spent opening irrelevant assets,
3) governance is supported by showing where and how terms matched, aiding audit and compliance processes, and
4) consistency is reinforced by revealing glossary and semantic relationships, which reduces misunderstanding and improves collaboration across teams.

How enhanced search works

When a user enters a query, the system searches across multiple fields like name, description, glossary terms, metadata, business names and table schema. With enhanced search transparency, each search result includes the list of text matches that were the basis for including the result, including the field that contained the text match, and a portion of the field’s text value before and after the text match, to provide context. The UI uses this information to display the returned text with the text match highlighted.

For example, a steward searches for “revenue forecasting,” and an asset is returned with the name “Sales Forecasting Dataset Q2” and a description that contains “projected sales figures.” The word sales is highlighted in the name and description, in both the search result and the text matches panel, because sales is a synonym for revenue. The About this result panel also shows that forecast was matched in the schema field name sales_forecast_q2.

Solution overview

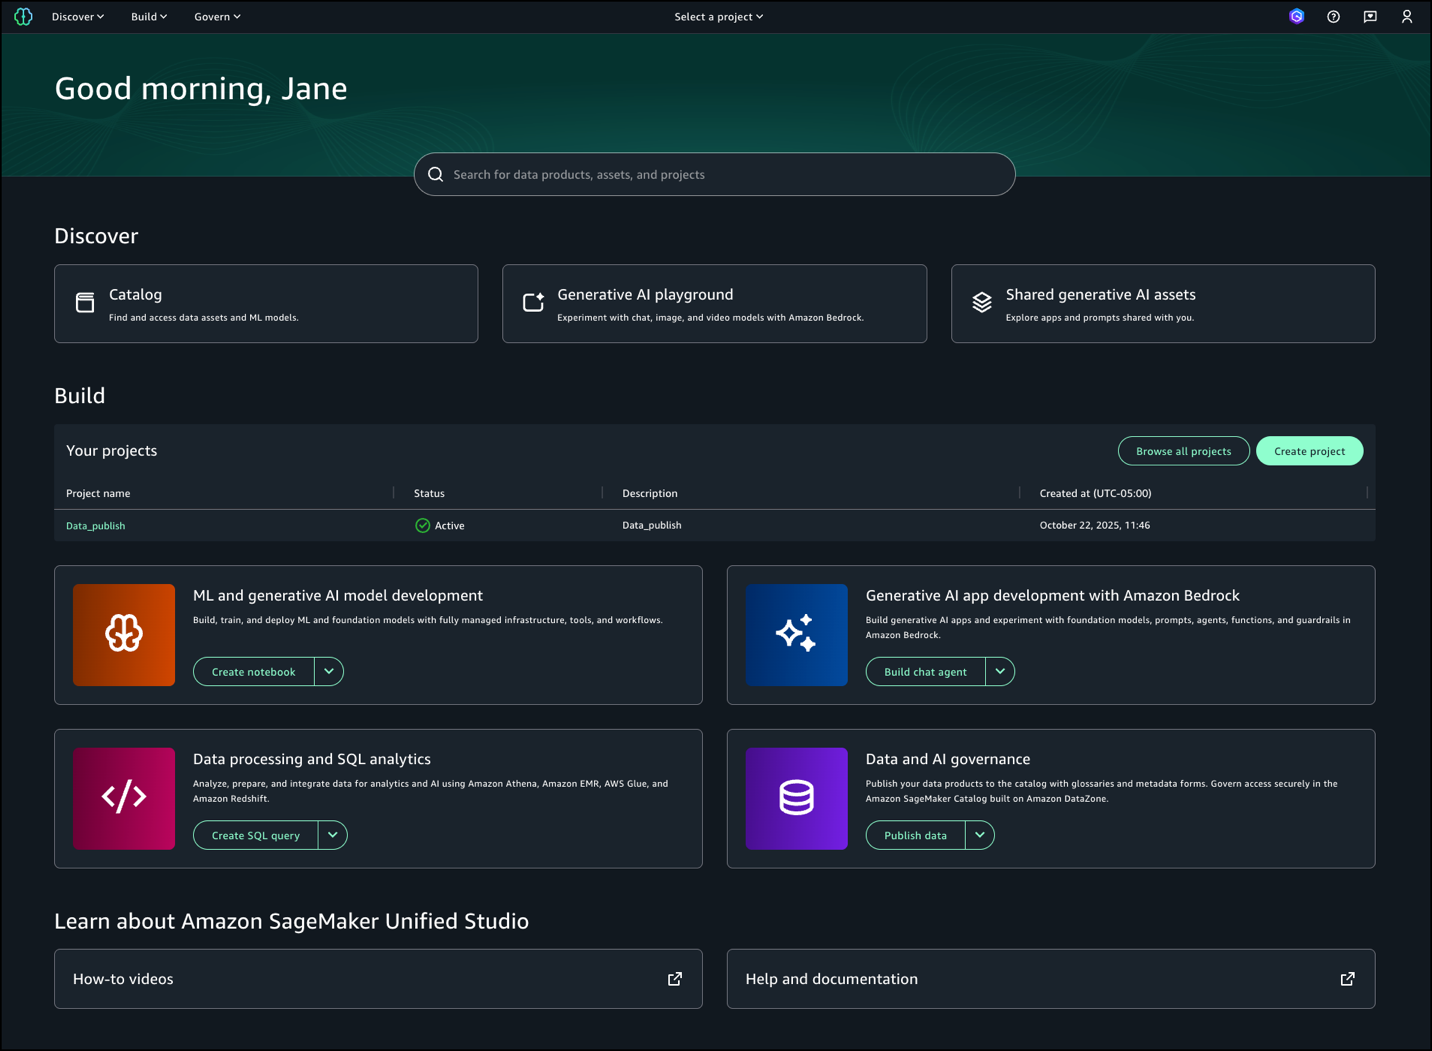
In this section we demonstrate how to use the enhanced search features. In this example, we will be demonstrating the use in a marketing campaign where we need user preference data. While we have multiple datasets on users, we will demonstrate how enhanced search simplifies the discovery experience.

Prerequisites

To test this solution you should have an Amazon SageMaker Unified Studio domain set up with a domain owner or domain unit owner privileges. You should also have an existing project to publish assets and catalog assets. For instructions to create these assets, see the Getting started guide.

In this example we created a project named Data_publish and loaded data from the Amazon Redshift sample database. To ingest the sample data to SageMaker Catalog and generate business metadata, see Create an Amazon SageMaker Unified Studio data source for Amazon Redshift in the project catalog.

Asset discovery with explainable search

To find assets with explainable search:

  1. Log in to SageMaker Unified Studio.
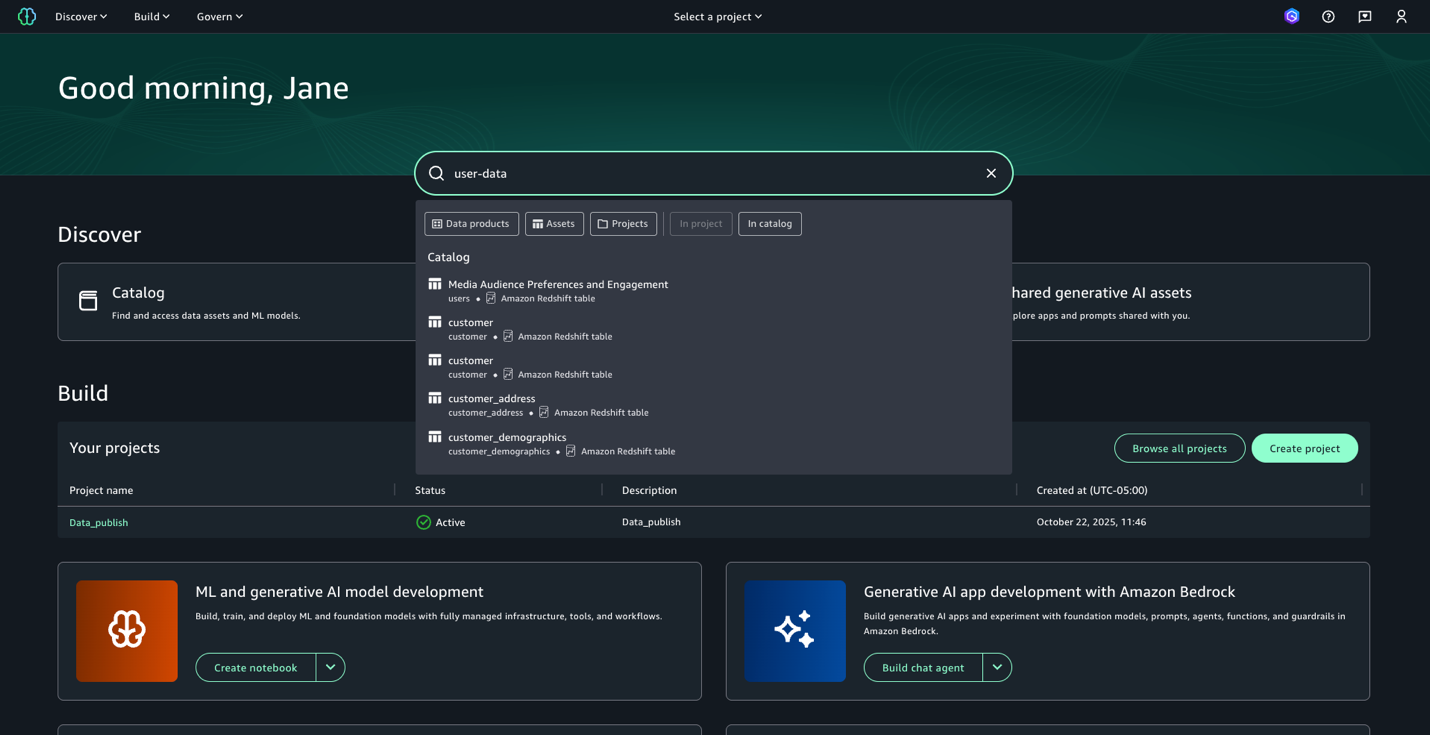
  2. Enter the search text user-data. While we get the search results in this view, we want to get further details on each of these datasets. Press enter to go to full search.
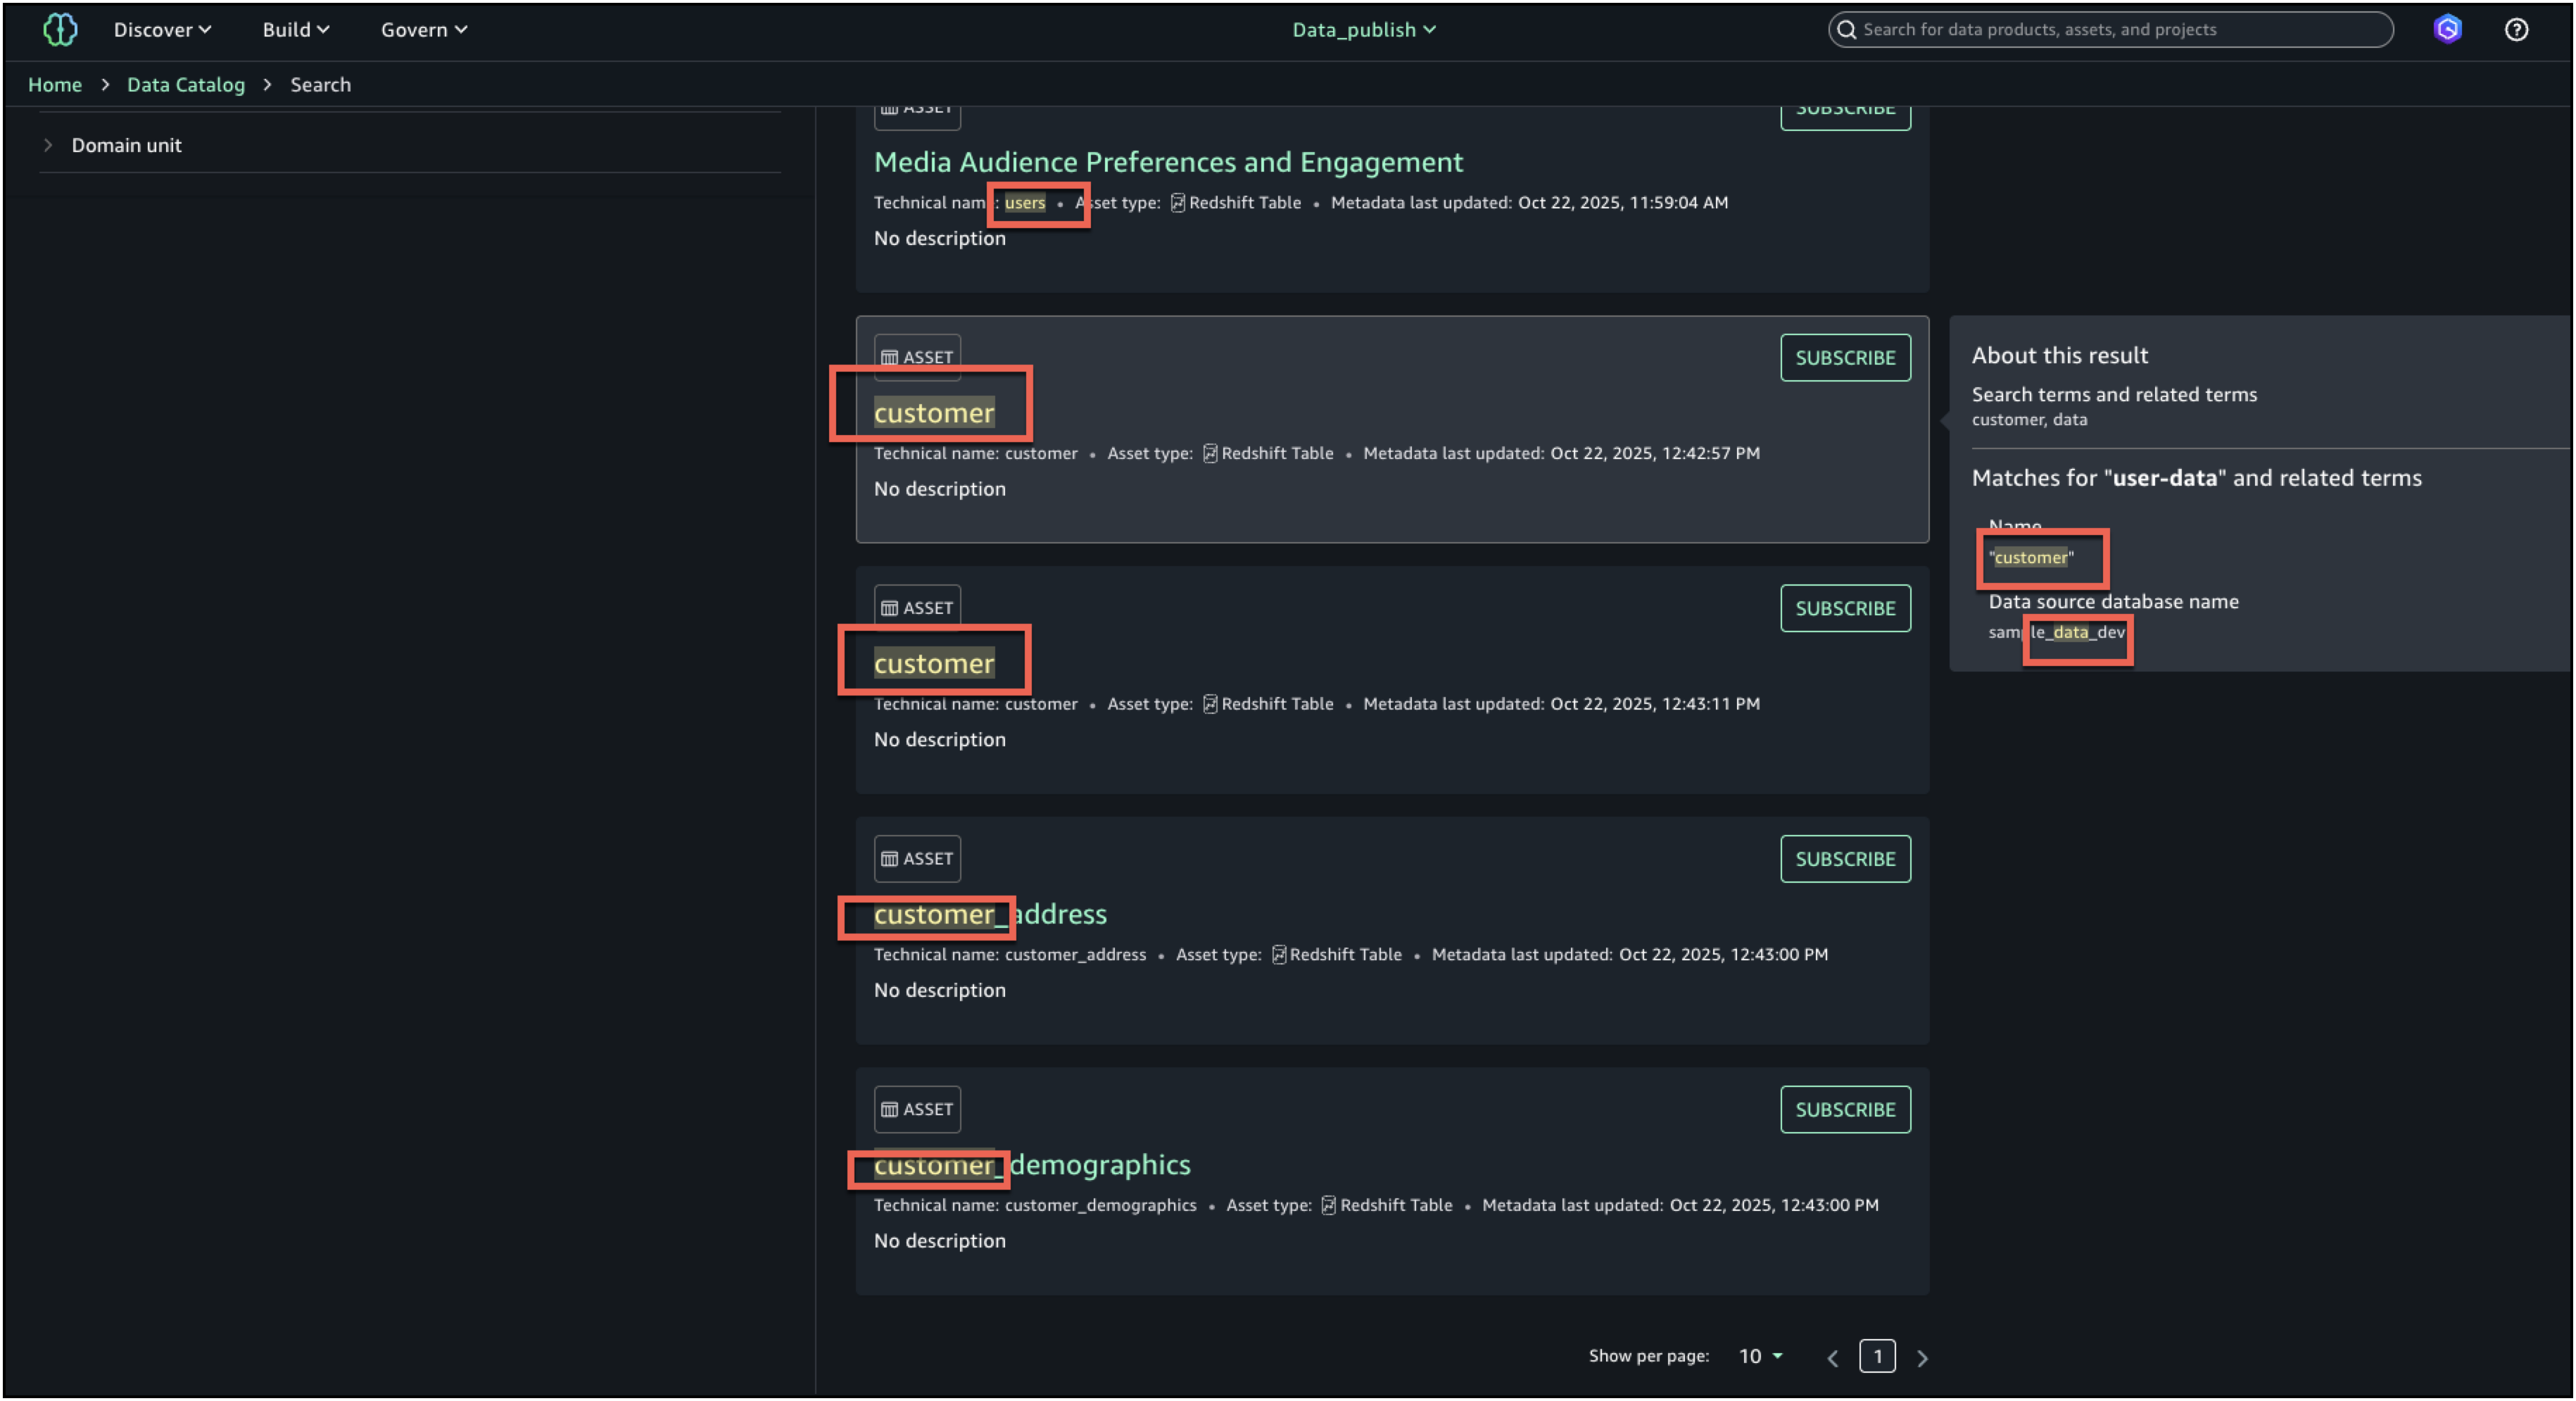
  3. In full search, search results are returned when there are text matches based on keyword search, starts with, synonym, and semantic search. Text matches are highlighted within the searchable content that is shown for each result: in the name, description, and glossary terms.
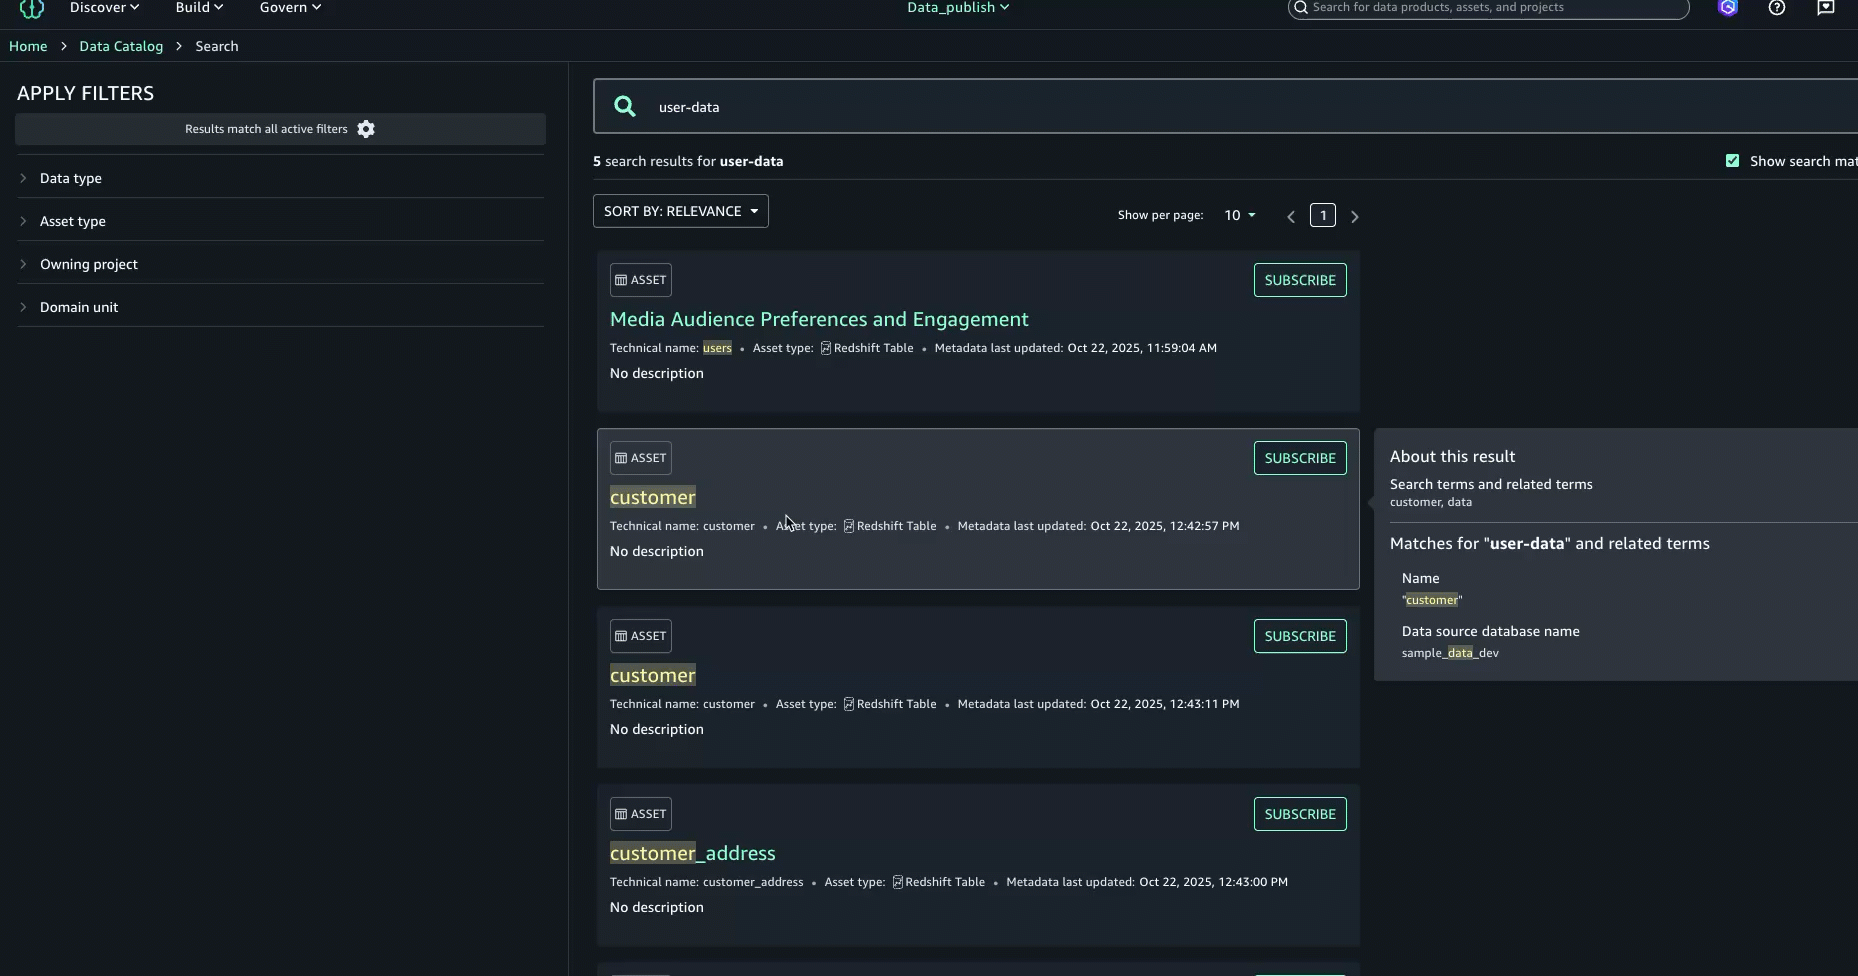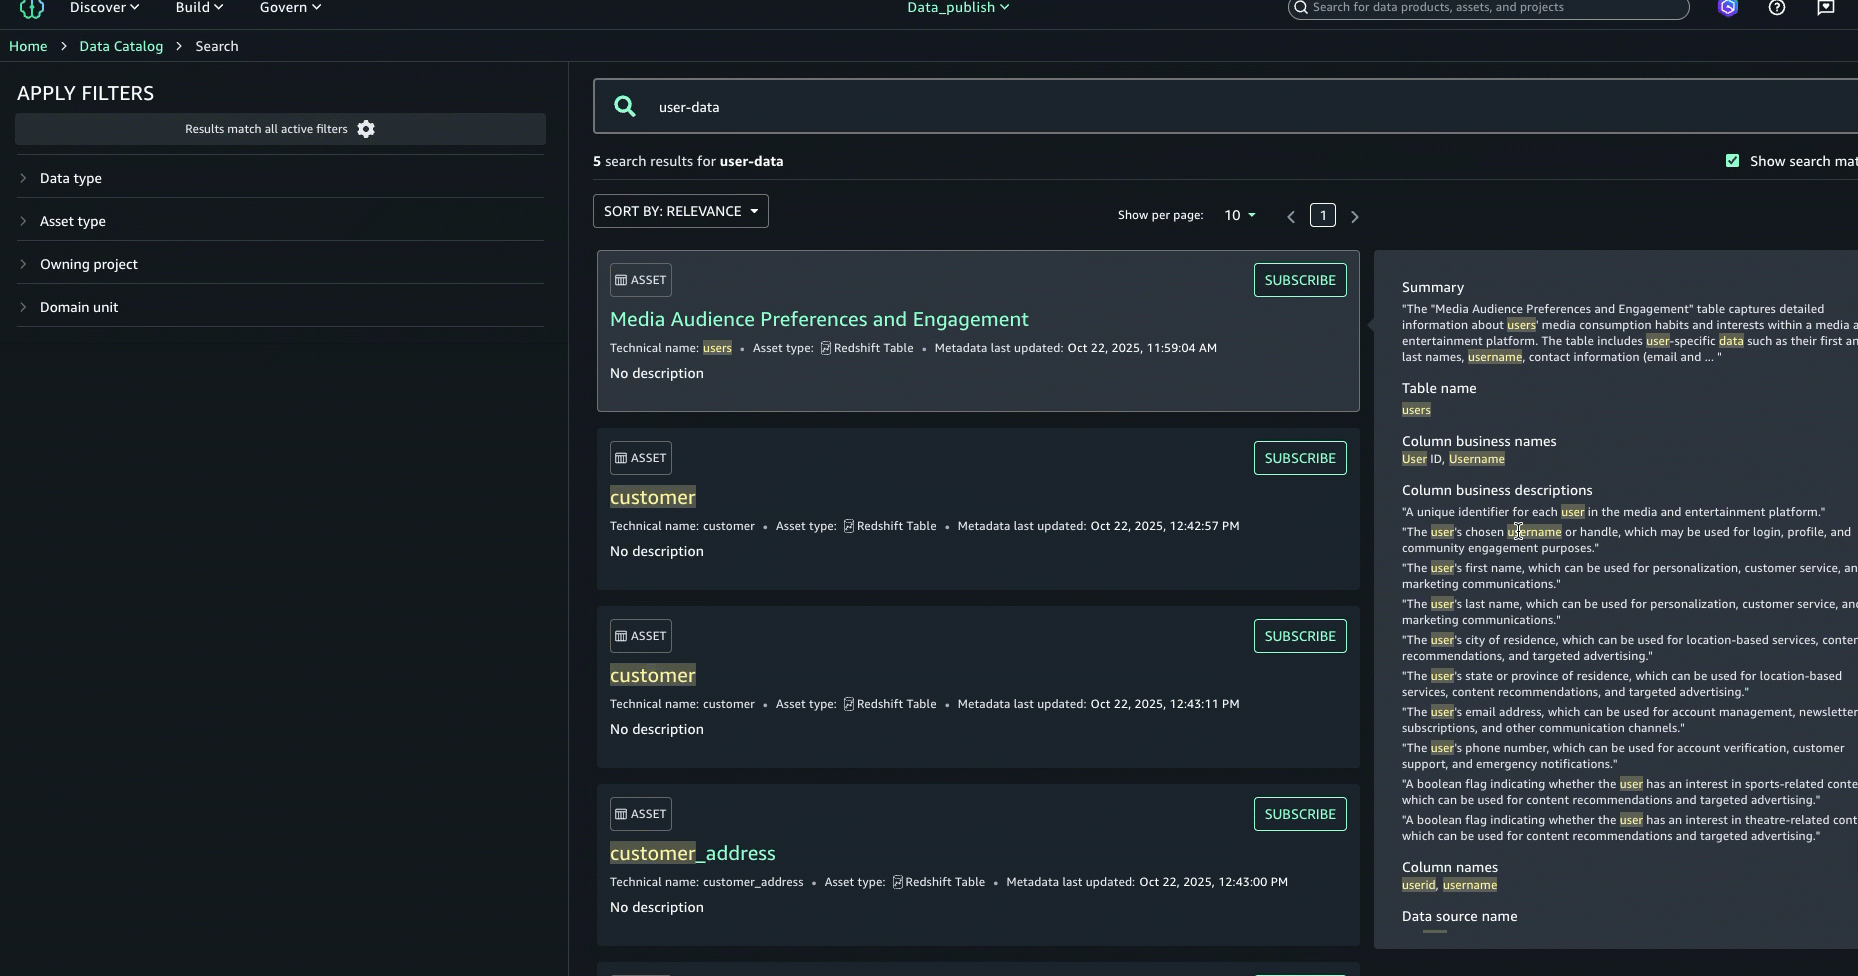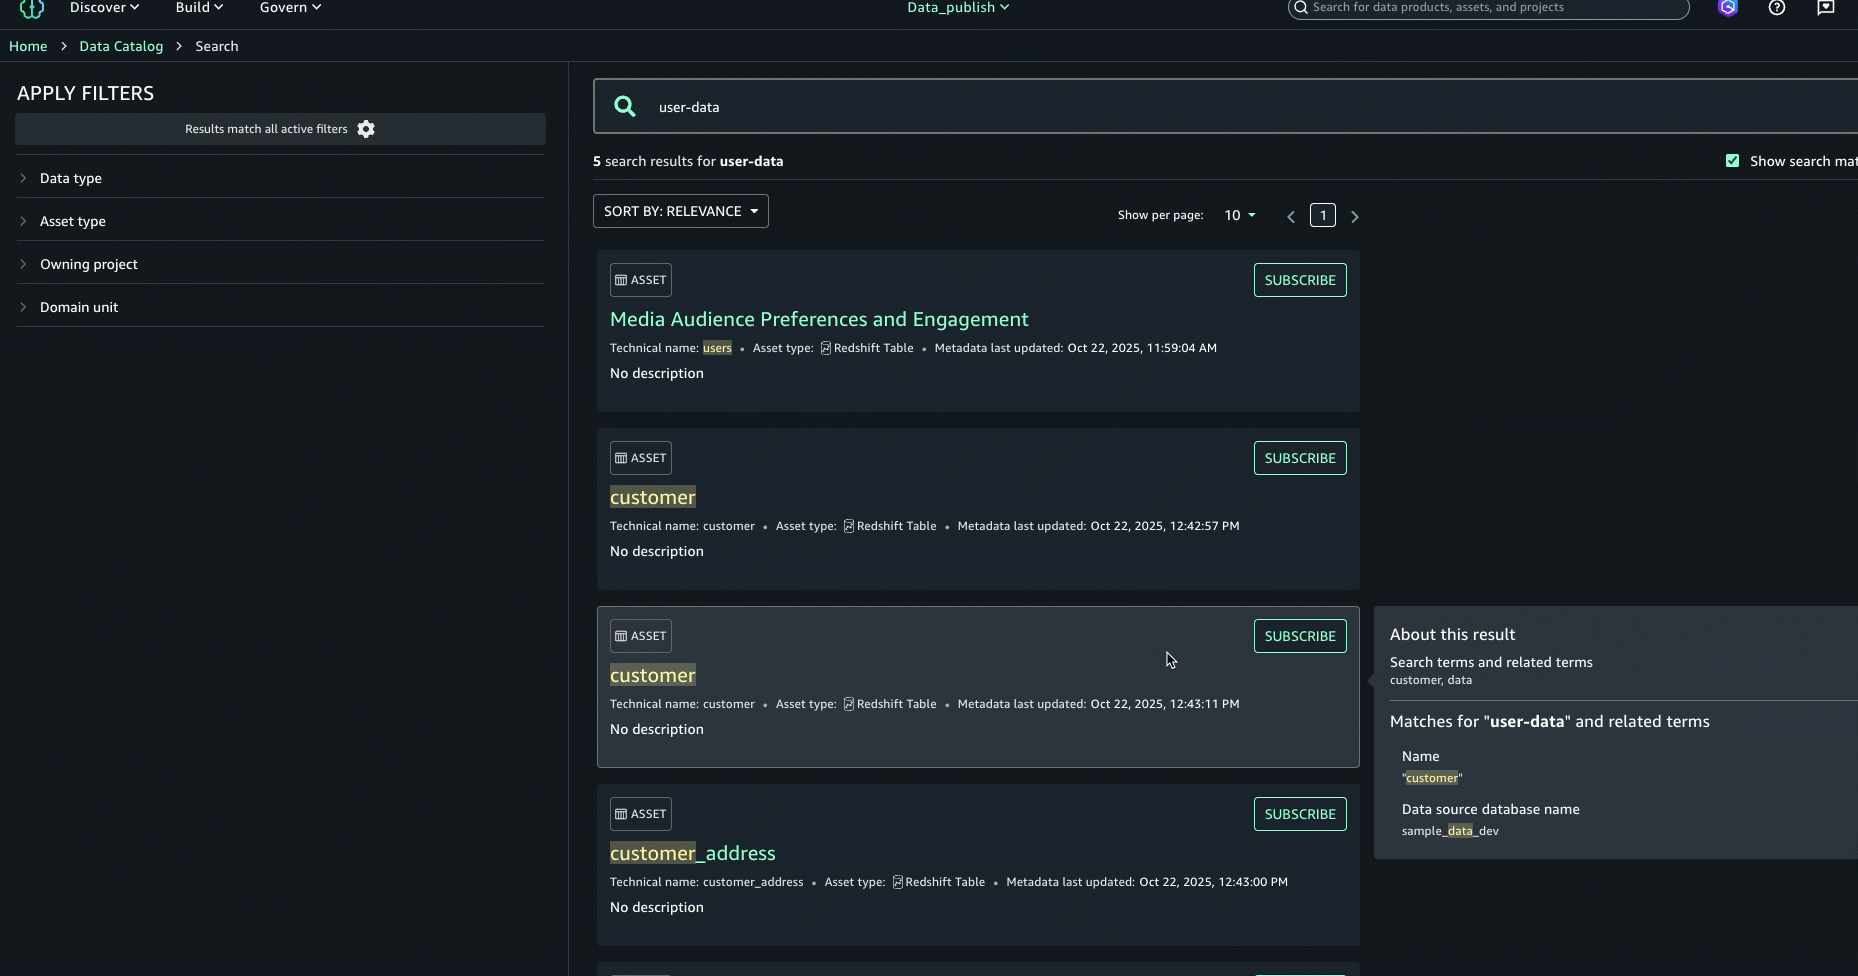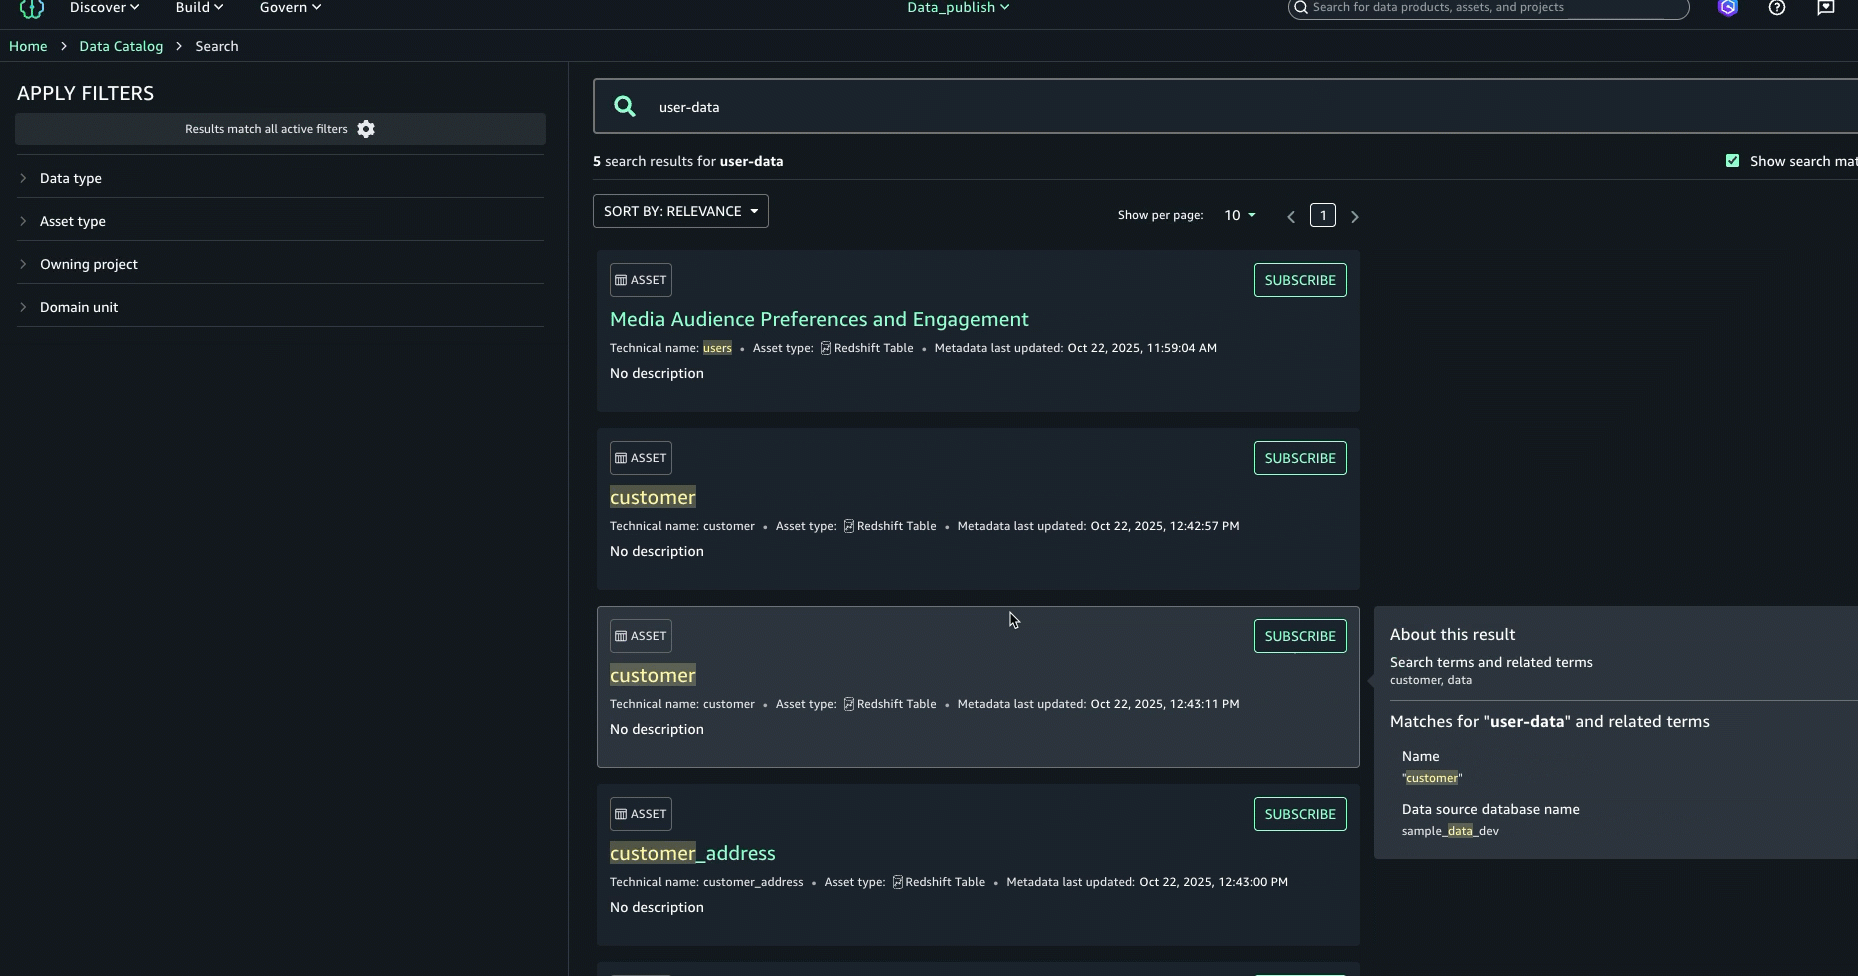
  4. To further enhance the discovery experience and find the right asset, you can look at the About this result panel on the right and see the other text matches, for example, in the summary, table name, data source database name, or column business name, to better understand why the result was included.
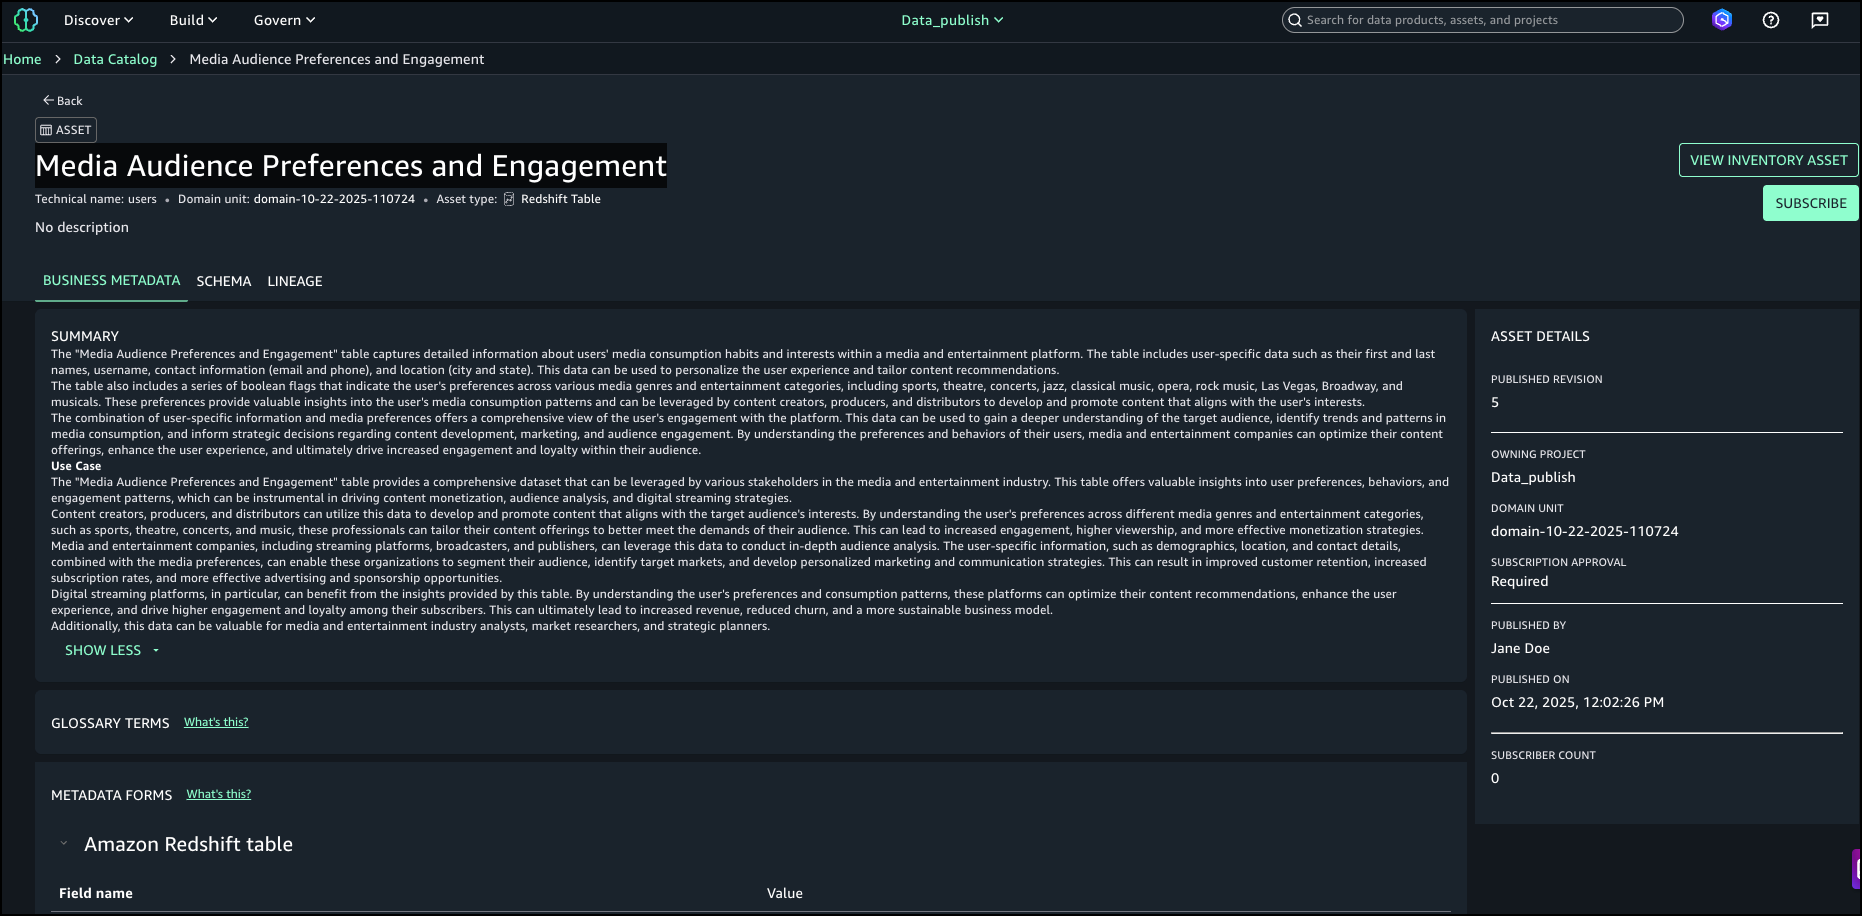
  5. After examining the search results and text match explanations, we identified the asset named Media Audience Preferences and Engagement as the right asset for the campaign and selected it for analysis.

Conclusion

Enhanced search transparency in Amazon SageMaker Unified Studio transforms data discovery by providing clear visibility into why assets appear in search results. The inline highlighting and detailed match explanations help users quickly identify relevant datasets while building trust in the data catalog. By showing exactly which metadata fields matched their queries, users spend less time evaluating irrelevant assets and more time analyzing the right data for their projects.

Enhanced search is now available in AWS Regions where Amazon SageMaker is supported.

To learn more about Amazon SageMaker, see the Amazon SageMaker documentation.


About the authors

Ramesh H Singh

Ramesh H Singh

Ramesh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon DataZone team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology.

Pradeep Misra

Pradeep Misra

Pradeep is a Principal Analytics and Applied AI Solutions Architect at AWS. He is passionate about solving customer challenges using data, analytics, and AI/ML. Outside of work, Pradeep likes exploring new places, trying new cuisines, and playing board games with his family. He also likes doing science experiments, building LEGOs and watching anime with his daughters.

Ron Kyker

Ron Kyker

Ron is a Principal Engineer with Amazon DataZone at AWS, where he helps drive innovation, solve complex problems, and set the bar for engineering excellence for his team. Outside of work, he enjoys board gaming with friends and family, movies, and wine tasting.

Rajat Mathur

Rajat Mathur

Rajat is a Software Development Manager at AWS, leading the Amazon DataZone and SageMaker Unified Studio engineering teams. His team designs, builds, and operates services which make it faster and straightforward for customers to catalog, discover, share, and govern data. With deep expertise in building distributed data systems at scale, Rajat plays a key role in advancing the data analytics and AI/ML capabilities of AWS.

Kyle Wong

Kyle Wong

Kyle is a Software Engineer at AWS based in San Francisco, where he works on the Amazon DataZone and SageMaker Unified Studio team. His work has been primarily at the intersection of data, analytics, and artificial intelligence, and he is passionate about developing AI-powered solutions that address real-world customer challenges.

Supercharging the ML and AI Development Experience at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/supercharging-the-ml-and-ai-development-experience-at-netflix-b2d5b95c63eb

Supercharging the ML and AI Development Experience at Netflix with Metaflow

Shashank Srikanth, Romain Cledat

Metaflow — a framework we started and open-sourced in 2019 — now powers a wide range of ML and AI systems across Netflix and at many other companies. It is well loved by users for helping them take their ML/AI workflows from prototype to production, allowing them to focus on building cutting-edge systems that bring joy and entertainment to audiences worldwide.

Metaflow allows users to:

  1. Iterate and ship quickly by minimizing friction
  2. Operate systems reliably in production with minimal overhead, at Netflix scale.

Metaflow works with many battle-hardened tooling to address the second point — among them Maestro, our newly open-sourced workflow orchestrator that powers nearly every ML and AI system at Netflix and serves as a backbone for Metaflow itself.

In this post, we focus on the first point and introduce a new Metaflow functionality, Spin, that helps users accelerate their iterative development process. By the end, you’ll have a solid understanding of Spin’s capabilities and learn how to try it out yourself with Metaflow 2.19.

Iterative development in ML and AI workflows

Developing a Metaflow flow with cards in VSCode

To understand our approach to improving the ML and AI development experience, it helps to consider how these workflows differ from traditional software engineering.

ML and AI development revolves not just around code but also around data and models, which are large, mutable, and computationally expensive to process. Iteration cycles can involve long-running data transformations, model training, and stochastic processes that yield slightly different results from run to run. These characteristics make fast, stateful iteration a critical part of productive development.

This is where notebooks — such as Jupyter, Observable, or Marimo — shine. Their ability to preserve state in memory allows developers to load a dataset once and iteratively explore, transform, and visualize it without reloading or recomputing from scratch. This persistent, interactive environment turns what would otherwise be a slow, rigid loop into a fluid, exploratory workflow — perfectly suited to the needs of ML and AI practitioners.

Because ML and AI development is computationally intensive, stochastic, and data- and model-centric, tools that optimize iteration speed must treat state management as a first-class design concern. Any system aiming to improve the development experience in this domain must therefore enable quick, incremental experimentation without losing continuity between iterations.

New: rapid, iterative development with spin

At first glance, Metaflow code looks like a workflow — similar to Airflow — but there’s another way to look at it: each Metaflow @step serves as a checkpoint boundary. At the end of every step, Metaflow automatically persists all instance variables as artifacts, allowing the execution to resume seamlessly from that point onward. The below animation shows this behavior in action:

An animated GIF showing how resume can be used in Metaflow. The GIF shows how using `flow.py resume join` makes Metaflow clone previously executed steps and resumes the computation from the `join` step and continues executing till the end of the flow.
Using resume in Metaflow

In a sense, we can consider a @step similar to a notebook cell: it is the smallest unit of execution that updates state upon completion. It does have a few differences that address the issues with notebook cells:

  • The execution order is explicit and deterministic: no surprises due to out-of-order cell execution;
  • The state is not hidden: state is explicitly stored as self. variables as shared state, which can be discovered and inspected;
  • The state is versioned and persisted making results more reproducible.

While Metaflow’s resume feature can approximate the incremental and iterative development approach of notebooks, it restarts execution from the selected step onward, introducing more latency between iterations. In contrast, a notebook allows near-instant feedback by letting users tweak and rerun individual cells while seamlessly reusing data from earlier cells held in memory.

The new spin command in Metaflow 2.19 addresses this gap. Similar to executing a single notebook cell, it quickly executes a single Metaflow @step — with all the state carried over from the parent step. As a result, users can develop and debug Metaflow steps as easily as a cell in a notebook.

The effect becomes clear when considering the three complementary execution modes — run, resume, and spin — side by side, mapping them to the corresponding notebook behavior:

Diagram showing the various modes of execution in Metaflow: Run, Resume and Spin
Run, Resume and Spin “modes”

Another major difference isn’t just what gets executed, but what gets recorded. Both run and resume create a full, versioned run with complete metadata and artifacts, while spin skips tracking altogether. It’s built for fast, throw-away iterations during development.

The one-minute clip below illustrates a typical iterative development workflow that alternates between run and spin. In this example, we are building a flow that reads a dataset from a Parquet file and trains a separate model for each product category, focusing on computer-related categories.

As shown in the video, we start by creating a flow from scratch and running a minimal version of it to persist test artifacts — in this case, a Parquet dataset. From there, we can use spin to iterate on one step at a time, incrementally building out the flow, for example, by adding the parallel training steps demonstrated in the clip.

Once the flow has been iterated on locally, it can be seamlessly deployed to production orchestrators like Maestro or Argo, and scaled up on compute platforms such as AWS Batch, Titus, Kubernetes and more. Thus, the experience is as smooth as developing in a notebook, but the outcome is a production-ready, scalable workflow, implemented as an idiomatic Python project!

Spin up smooth development in VSCode/Cursor

Instead of typing run and spin manually in the terminal, we can bind them to keyboard shortcuts. For example, the simple metaflow-dev VS Code extension (works with Cursor as well) maps Ctrl+Opt+R to run and Ctrl+Opt+S to spin. Just hack away, hit Ctrl+Opt+S, and the extension will save your file and spin the step you are currently editing.

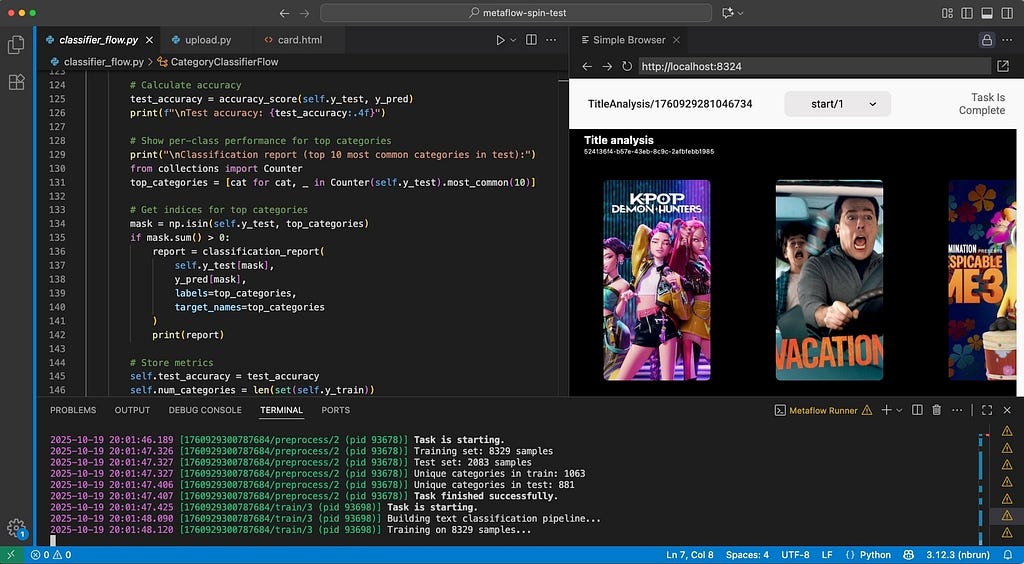
One area where spin truly shines is in creating mini-dashboards and reports with Metaflow Cards. Visualization is another strong point of notebooks but the combination of spin and cards makes Metaflow a very compelling alternative for developing real-time and post-execution visualizations. Developing cards is inherently iterative and visual (much like building web pages) where you want to tweak code and see the results instantly. This workflow is readily available with the combination of VSCode/Cursor, which includes a built-in web-view, the local card viewer, and spin.

To see the trio of tools — along with the VS Code extension — in action, in this short clip we add observability to the train step that we built in the earlier example:

A major benefit of Metaflow Cards is that we don’t need to deploy any extra services, data streams, and databases for observability. Just develop visual outputs as above, deploy the flow, and wehave a complete system in production with reporting and visualizations included.

Spin to the next level: injecting inputs, inspecting outputs

Spin does more than just run code — it also lets us take full control of a spun @step’s inputs and outputs, enabling a range of advanced patterns.

In contrast to notebooks, we can spin any arbitrary @step in a flow using state from any past run, making it easy to test functions with different inputs. For example, if we have multiple models produced by separate runs, we could spin an inference step, supplying a different model run each time.

We can also override artifact values or inject arbitrary Python objects — similar to a notebook cell — for spin. Simply specify a Python module with an ARTIFACTS dictionary:

ARTIFACTS = {
"model": "kmeans",
"k": 15
}

and point spin at the module:

spin train --artifacts-module artifacts.py

By default spin doesn’t persist artifacts, but we can easily change this by adding –persist. Even in this case, artifacts are not persisted in the usual Metaflow datastore but to a directory-specific location which you can easily clean up after testing. We can access the results with the Client API as usual — just specify the directory you want to inspect with inspect_spin:

from metaflow import inspect_spin

inspect_spin(".")
Flow("TrainingFlow").latest_run["train"].task["model"].data

Being able to inspect and modify a step’s inputs and outputs on the fly unlocks a powerful use case: unit testing individual steps. We can use spin programmatically through the Runner API and assert the results:

from metaflow import Runner

with Runner("flow.py").spin("train", persist=True) as spin:
assert spin.task["model"].data == "kmeans"

Making AI agents spin

In addition to speeding up development for humans, spin turns out to be surprisingly handy for coding agents too. There are two major advantages to teaching AI how to spin:

  1. It accelerates the development loop. Agents don’t naturally understand what’s slow, or why speed matters, so they need to be nudged to favor faster tools over slower ones.
  2. It helps surface errors faster and contextualizes them to a specific piece of code, increasing the chance that the agent is able to fix errors by itself.

Metaflow users are already using Claude Code; spin makes this even easier. In the example below, we added the following section in a CLAUDE.md file:

## Developing Metaflow code
Follow this incremental development workflow that ensures quick iterations
and correct results. You must create a flow incrementally, step by step
following this process:
1. Create a flow skeleton with empty `@step`s.
2. Add a data loading step.
3. `run` the flow.
4. Populate the next step and use `spin` to test it with the correct inputs.
5. `run` the flow to record outputs from the new step.
5. Iterate on (4–5) until all steps have been implemented and work correctly.
6. `run` the whole flow to ensure final correctness.

To test a flow, run the flow as follows
```
python flow.py - environment=pypi run
```

Do this once before running `spin`.
As you are building the flow, you `spin` to test steps quickly.
For instance
```
python flow.py - environment=pypi spin train
```

Just based on these quick instructions, the agent is able to use spin effectively. Take a look at the following inspirational example that one-shots Claude to create a flow, along the lines of our earlier examples, which trains a classifier to predict product categories:

In the video, we can see Claude using spin around the 45-second mark to test a preprocess step. The step initially fails due to a classic data science pitfall: during testing, Claude samples only a small subset of data, causing some classes to be underrepresented. The first spin surfaces the issue, which Claude then fixes by switching to stratified sampling — and finally does another spin to confirm the fix, before proceeding to complete the task.

The inner loop of end-to-end ML/AI

To circle back to where we started, our motivation for adding spin — and for creating Metaflow in the first place — is to accelerate development cycles so we can deliver more joy to our subscribers, faster. Ultimately, we believe there’s no single magic feature that makes this possible. It takes all parts of an ML/AI platform working together coherently — spin included.

From this perspective, it’s useful to place spin in the context of other Metaflow features. It’s designed for the innermost loop of model and business-logic development, with the added benefit of supporting unit testing during deployment, as shown in the overall blueprint of the Metaflow toolchain below.

Metaflow tool-chain.
Metaflow tool-chain

In this diagram, the solid blue boxes represent different Metaflow commands, while the blue text denotes decorators and other features. In particular, note the Shared Functionality box — another key focus area for us over the past year — which includes configuration management and custom decorators. These capabilities let domain-specific teams and platform providers tailor Metaflow to their own use cases. Following our ethos of composability, all of these features integrate seamlessly with spin as well.

Another key design philosophy of Metaflow is to let projects start small and simple, adding complexity only when it becomes necessary. So don’t be overwhelmed by the diagram above. To get started, install Metaflow easily with

pip install metaflow

and take your first baby @steps for a spin! Check out the docs and for questions, support, and feedback, join the friendly Metaflow Community Slack.

Acknowledgments

We would like to thank our partners at Outerbounds, and particularly Ville Tuulos, Savin Goyal, and Madhur Tandon, for their collaboration on this feature, from initial ideation to review, testing and documentation. We would also like to acknowledge the rest of the Model Development and Management team (Maria Alder, David J. Berg, Shaojing Li, Rui Lin, Nissan Pow, Chaoying Wang, Regina Wang, Seth Yang, Darin Yu) for their input and comments.


Supercharging the ML and AI Development Experience at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Новите данни на МВР за катастрофите

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/mvr-data/

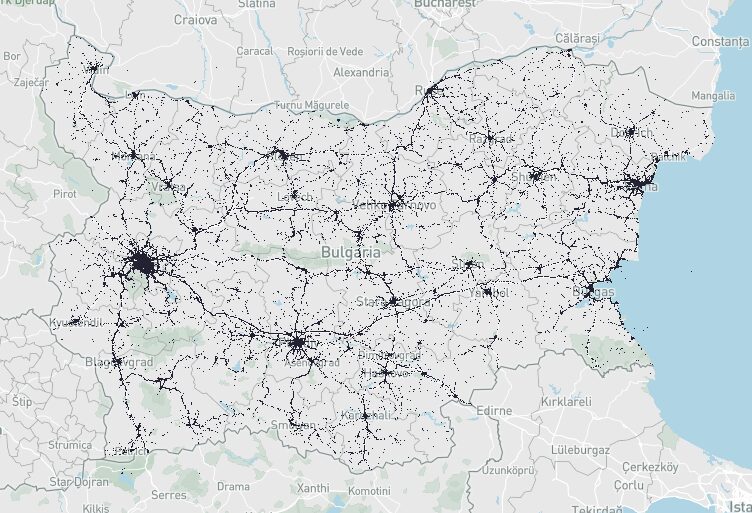
През май Мартин пусна картата Черна писта, която показва нагледно данни получени по ЗДОИ от МВР за катастрофите в България с информация за местоположение, време, ситуация и жертви. Данните покриваха периода от 1-ви януари 2021 до 13-ти април 2025. Това прави 162.3 средно на ден. Съдържаха 253674 записа от които 75929 или 30% нямат известно местоположение. Пуснах анализ на тези данни показващи недостатъци в методологията на МВР като например координатите на инцидентите.

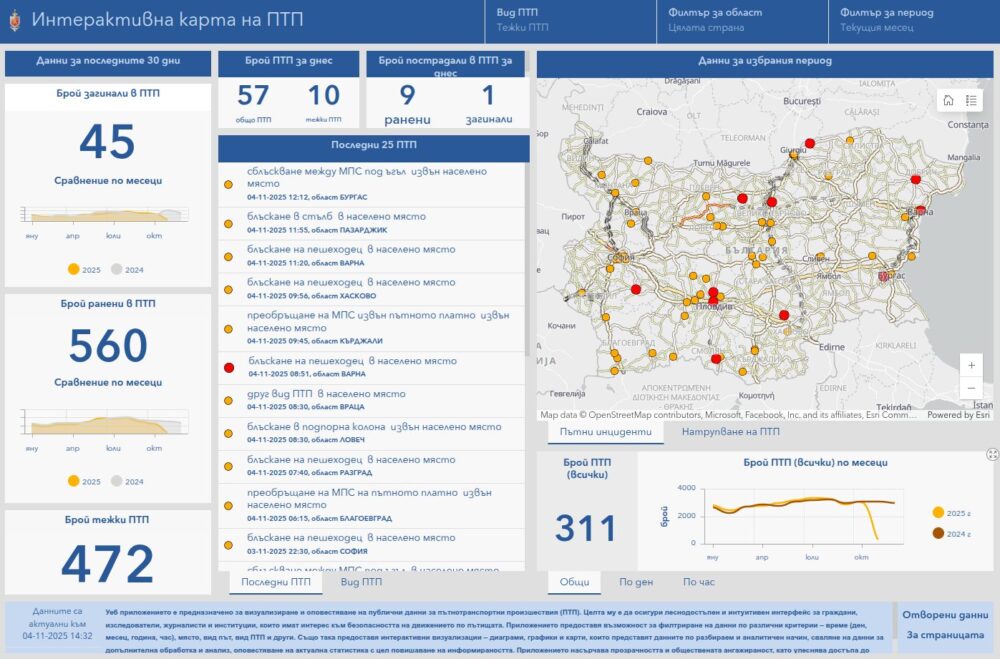
Два месеца по-късно Мартин писа, че получава отказ от МВР за последните данни. Малко по-късно сподели комуникацията с тях. Накратко МВР отказва да изпрати същата справка от последните месеци, тъй като работила върху собствена карта. Тази карта виждате долу. Представлява табло, което дава статистика и информация с последните случаи. Има филтри за райони, видове ПТП-та и периоди.

Таблото не е лошо и като плюс има отворени данни като линк долу вдясно. Това е важно, защото както съм изтъквал многократно, трябват ни суровите данни, а не интерпретация или статистика подбрана от институцията създаваща данните. Това създава риск от изкривяване на фактите и предотвратява възможността да проверяваме твърденията им и да си вадим изводи за работата. Спира ни да задаваме и въпроси, като например защо част от данните липсват или ПТП-та се намират в средата на парк или море.

Настоящите данни на МВР може да свалим са под формата на SHP файл, който е труден за използване от повечето хора. Отделно самият сайт предотвратява автоматичното сваляне, а гео сървърът им е затворен, което спира доста интерактивни приложения.

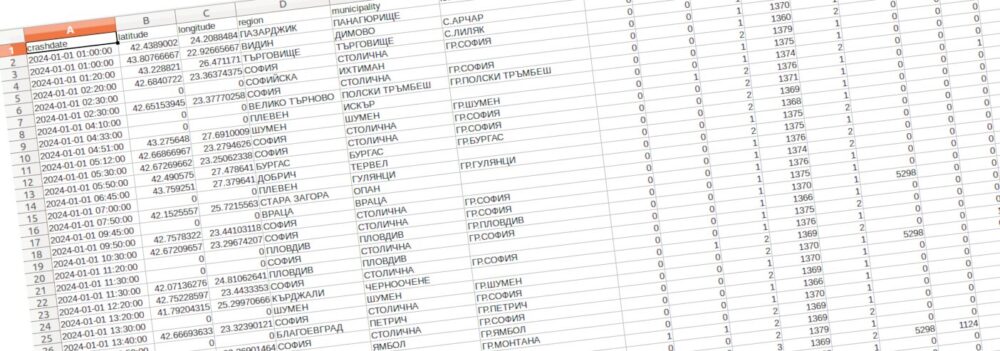
Затова направих скрипт, който всеки ден да сваля данните и да ги обръща в нещо по-използваемо. Може да ги свалите на този линк. Техния архив се обновява ежедневно и съдържа данни от началото на 2024-та. Към този момент съдържа 64255 записа между 1-ви януари 2024 и 4-ти ноември 2025. Това прави 95.5 на ден. От тях 3992 или 6.2% са без известно местоположение.

Тъй като и двете справки покриват цялата 2024-та г. може да направим бързо сравнение. Докато данните получени от Мартин и налични в Черна писта съдържат 63183 записа от които 58051 или почти 92% са с известно местоположение. За сравнение, наличните катастрофи на картата на МВР и отворените им данни са 34664 или почти наполовина по-малко. От тях 31541 или 91% са с известно местоположение.

Това означава, че по някаква причина отворените сега данни от МВР съдържат доста по-малко случаи от тези, които са предоставили на Мартин. Подробно вглеждане в разликите би помогнало да се разбере какво липсва, дали е имало дублиране преди или просто са изчистили грешки. Положителното поне е, че данните на МВР съдържат повече параметри и са публикували описание на номенклатурите и какво означават. Липсва номенклатура за crashtype, но съм я извадил от кода им във файла METADATA. Данните на Черна писта са публикувани на страницата. Ако някой открие различията и има обяснение кои катастрофи липсват и защо, ще се радвам да сподели в коментарите.

The post Новите данни на МВР за катастрофите first appeared on Блогът на Юруков.

Incus 6.18 released

Post Syndicated from jzb original https://lwn.net/Articles/1044987/

Version
6.18
of the Incus container and virtual-machine management system
has been released. Notable changes in this release include new
configuration keys for providing credentials to systemd, BPF token
delegation, VirtIO support for sound cards, the ability to export ISO
volumes, improvements to the IncusOS command-line utility, and more.

[$] Julia 1.12 brings progress on standalone binaries and more

Post Syndicated from jake original https://lwn.net/Articles/1044280/

Julia is a modern programming
language that is of particular interest to scientists due to its high
performance combined with language features such as Lisp-style macros, an
advanced type system, and multiple dispatch. We last looked at Julia in January on the occasion of
its 1.11 release. Early in October Julia 1.12
appeared
, bringing a handful of quality-of-life improvements for Julia
programmers, most notably support, though still experimental and limited,
for the creation of binaries.

Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1044949/

Security updates have been issued by Debian (dcmtk, geographiclib, gimp, pure-ftpd, and ruby-rack), Fedora (dotnet9.0), Oracle (expat, kernel, tigervnc, xorg-x11-server, and xorg-x11-server-Xwayland), Red Hat (git, mariadb:10.5, multiple packages, osbuild-composer, pcs, sssd, and tigervnc), SUSE (kernel and redis), and Ubuntu (google-guest-agent).

The End Of Legacy SIEM: Why It’s Time To Take Command

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/dr-the-end-of-legacy-siem-time-to-take-command

Security teams have long depended on SIEM tools as the backbone of threat detection and response. But the threat landscape, and the technology required to defend against it, has changed dramatically.

Rapid7’s new whitepaper, The End of Legacy SIEM and the Rise of Incident Command, examines why legacy SIEM models can no longer keep up with the scale and complexity of modern attacks, and why next-gen SIEMs (like that offered by Rapid7) combined with exposure management capabilities is the better choice in combatting modern enemies.

A turning point for the SOC

When SIEM first emerged, it was a breakthrough. For the first time, organizations could centralize log data, generate compliance reports, and detect threats from a single pane of glass. But two decades later, that approach is showing its age.

Today, data is distributed across cloud, on-prem, and hybrid environments. Adversaries are using artificial intelligence to automate and accelerate increasingly complex attacks that are escaping detection. Analysts are overwhelmed by alert fatigue and unpredictable costs that hamper visibility.

Legacy SIEM tools were built to collect data. They rely on rigid pricing models, static correlation rules, and constant manual upkeep. These systems slow down investigations and prevent analysts from focusing on the alerts that truly matter. Modern attackers exploit exposures faster than human teams can respond. Without automation, context, and clear prioritization, organizations remain in a reactive state. 

What comes after SIEM?

The whitepaper outlines how the security industry is shifting toward a unified approach that combines SIEM, Security Orchestration and Automation (SOAR), Attack Surface Management (ASM), and threat intelligence in one platform, augmented by artificial intelligence.

This new model emphasizes automation, machine learning, and contextual awareness while collecting data from a wider variety of sources than SIEMs were originally designed for. It gives security teams the ability to identify and act on high-impact threats quickly. It also changes how organizations think about risk, focusing less on collecting alerts and more on understanding exposure across assets, identities, and vulnerabilities.

Introducing Rapid7 Incident Command

At the center of this shift is Rapid7 Incident Command, a unified platform that redefines modern detection and response. Trained on trillions of real-world alerts from Rapid7’s 24/7 Managed Detection and Response (MDR) service, Incident Command can accurately classify benign activity 99.93 percent of the time. This precision saves hundreds of analyst hours each week and drastically reduces noise.

Incident Command connects exposure data directly to detection logic, helping analysts see which threats are most likely to impact their organization. Built-in automation enables teams to isolate hosts, revoke credentials, or run response playbooks, while keeping humans in control of every action.

With asset-based pricing and a fast, cloud-based deployment model, organizations can scale visibility and response without the fear of surprise costs or drawn-out implementations.

A new chapter for defenders

Legacy SIEM served its purpose, but it was built for a different era. The modern SOC requires a platform that is unified, intelligent, and focused on outcomes.

The End of Legacy SIEM and the Rise of Incident Command explores how this transformation is reshaping detection and response for security teams everywhere.

Read the full whitepaper to learn why the future of SIEM is already here and how you can take command of what comes next.

Building a better testing experience for Workflows, our durable execution engine for multi-step applications

Post Syndicated from Olga Silva original https://blog.cloudflare.com/better-testing-for-workflows/

Cloudflare Workflows is our take on “Durable Execution.” They provide a serverless engine, powered by the Cloudflare Developer Platform, for building long-running, multi-step applications that persist through failures. When Workflows became generally available earlier this year, they allowed developers to orchestrate complex processes that would be difficult or impossible to manage with traditional stateless functions. Workflows handle state, retries, and long waits, allowing you to focus on your business logic.

However, complex orchestrations require robust testing to be reliable. To date, testing Workflows was a black-box process. Although you could test if a Workflow instance reached completion through an await to its status, there was no visibility into the intermediate steps. This made debugging really difficult. Did the payment processing step succeed? Did the confirmation email step receive the correct data? You couldn’t be sure without inspecting external systems or logs. 

Why was this necessary?

As developers ourselves, we understand the need to ensure reliable code, and we heard your feedback loud and clear: the developer experience for testing Workflows needed to be better.

The black box nature of testing was one part of the problem. Beyond that, though, the limited testing offered came at a high cost. If you added a workflow to your project, even if you weren’t testing the workflow directly, you were required to disable isolated storage because we couldn’t guarantee isolation between tests. Isolated storage is a vitest-pool-workers feature to guarantee that each test runs in a clean, predictable environment, free from the side effects of other tests. Being forced to have it disabled meant that state could leak between tests, leading to flaky, unpredictable, and hard-to-debug failures.

This created a difficult choice for developers building complex applications. If your project used Workers, Durable Objects, and R2 alongside Workflows, you had to either abandon isolated testing for your entire project or skip testing. This friction resulted in a poor testing experience, which in turn discouraged the adoption of Workflows. Solving this wasn’t just an improvement, it was a critical step in making Workflows part of any well-tested Cloudflare application.

Introducing isolated testing for Workflows

We’re introducing a new set of APIs that enable comprehensive, granular, and isolated testing for your Workflows, all running locally and offline with vitest-pool-workers, our testing framework that supports running tests in the Workers runtime workerd. This enables fast, reliable, and cheap test runs that don’t depend on a network connection.

They are available through the cloudflare:test module, with @cloudflare/vitest-pool-workers version 0.9.0 and above. The new test module provides two primary functions to introspect your Workflows:

  • introspectWorkflowInstance: useful for unit tests with known instance IDs

  • introspectWorkflow: useful for integration tests where IDs are typically generated dynamically.

Let’s walk through a practical example.

A practical example: testing a blog moderation workflow

Imagine a simple Workflow for moderating a blog. When a user submits a comment, the Workflow requests a review from workers-ai. Based on the violation score returned, it then waits for a moderator to approve or deny the comment. If approved, it calls a step.do to publish the comment via an external API.

Testing this without our new APIs would be impossible. You’d have no direct way to simulate the step’s outcomes and simulate the moderator’s approval. Now, you can mock everything.

Here’s the test code using introspectWorkflowInstance with a known instance ID:

import { env, introspectWorkflowInstance } from "cloudflare:test";

it("should mock a an ambiguous score, approve comment and complete", async () => {
   // CONFIG
   await using instance = await introspectWorkflowInstance(
       env.MODERATOR,
       "my-workflow-instance-id-123"
   );
   await instance.modify(async (m) => {
       await m.mockStepResult({ name: "AI content scan" }, { violationScore: 50 });
       await m.mockEvent({ 
           type: "moderation-approval", 
           payload: { action: "approved" },
       });
       await m.mockStepResult({ name: "publish comment" }, { status: "published" });
   });

   await env.MODERATOR.create({ id: "my-workflow-instance-id-123" });
   
   // ASSERTIONS
   expect(await instance.waitForStepResult({ name: "AI content scan" })).toEqual(
       { violationScore: 50 }
   );
   expect(
       await instance.waitForStepResult({ name: "publish comment" })
   ).toEqual({ status: "published" });

   await expect(instance.waitForStatus("complete")).resolves.not.toThrow();
});

This test mocks the outcomes of steps that require external API calls, such as the ‘AI content scan’, which calls Workers AI, and the ‘publish comment’ step, which calls an external blog API.

If the instance ID is not known, because you are either making a worker request that starts one/multiple Workflow instances with random generated ids, you can call introspectWorkflow(env.MY_WORKFLOW). Here’s the test code for that scenario, where only one Workflow instance is created:

it("workflow mock a non-violation score and be successful", async () => {
   // CONFIG
   await using introspector = await introspectWorkflow(env.MODERATOR);
   await introspector.modifyAll(async (m) => {
       await m.disableSleeps();
       await m.mockStepResult({ name: "AI content scan" }, { violationScore: 0 });
   });

   await SELF.fetch(`https://mock-worker.local/moderate`);

   const instances = introspector.get();
   expect(instances.length).toBe(1);

   // ASSERTIONS
   const instance = instances[0];
   expect(await instance.waitForStepResult({ name: "AI content scan"  })).toEqual({ violationScore: 0 });
   await expect(instance.waitForStatus("complete")).resolves.not.toThrow();
});

Notice how in both examples we’re calling the introspectors with await using – this is the Explicit Resource Management syntax from modern JavaScript. It is crucial here because when the introspector objects go out of scope at the end of the test, its disposal method is automatically called. This is how we ensure each test works with its own isolated storage.

The modify and modifyAll functions are the gateway to controlling instances. Inside its callback, you get access to a modifier object with methods to inject behavior such as mocking step outcomes, events and disabling sleeps.

You can find detailed documentation on the Workers Cloudflare Docs.

How we connected Vitest to the Workflows Engine

To understand the solution, you first need to understand the local architecture. When you run wrangler dev, your Workflows are powered by Miniflare, a simulator for testing Cloudflare Workers, and workerd. Each running workflow instance is backed by its own SQLite Durable Object, which we call the “Engine DO”. This Engine DO is responsible for executing steps, persisting state, and managing the instance’s lifecycle. It lives inside the local isolated Workers runtime.

Meanwhile, the Vitest test runner is a separate Node.js process living outside of workerd. This is why we have a Vitest custom pool that allows tests to run inside workerd called vitest-pool-workers. Vitest-pool-workers has a Runner Worker, which is a worker to run the tests with bindings to everything specified in the user wrangler.json file. This worker has access to the APIs under the “cloudflare:test” module. It communicates with Node.js through a special DO called Runner Object via WebSocket/RPC.

The first approach we considered was to use the test runner worker. In its current state, Runner worker has access to Workflow bindings from Workflows defined on the wrangler file. We considered also binding each Workflow’s Engine DO namespace to this runner worker. This would give vitest-pool-workers direct access to the Engine DOs where it would be possible to directly call Engine methods. 


While promising, this approach would have required undesirable changes to the core of Miniflare and vitest-pool-workers, making it too invasive for this single feature. 

Firstly, we would have needed to add a new unsafe field to Miniflare’s Durable Objects. Its sole purpose would be to specify the service name of our Engines, preventing Miniflare from applying its default user prefix which would otherwise prevent the Durable Objects from being found.

Secondly, vitest-pool-workers would have been forced to bind every Engine DO from the Workflows in the project to its runner, even those not being tested. This would introduce unwanted bindings into the test environment, requiring an additional cleanup to ensure they were not exposed to the user’s tests env.

The breakthrough

The solution is a combination of privileged local-only APIs and Remote Procedure Calls (RPC).

First, we added a set of unsafe functions to the local implementation of the Workflows binding, functions that are not available in the production environment. They act as a controlled access point, accessible from the test environment, allowing the test runner to get a stub to a specific Engine DO by providing its instance ID.

Once the test runner has this stub, it uses RPC to call specific, trusted methods on the Engine DO via a special RpcTarget called WorkflowInstanceModifier. Any class that extends RpcTarget has its objects replaced by a stub. Calling a method on this stub, in turn, makes an RPC back to the original object.


This simpler approach is far less invasive because it’s confined to the Workflows environment, which also ensures any future feature changes are safely isolated.

Introspecting Workflows with unknown IDs

When creating Workflows instances (either by create() or createBatch()) developers can provide a specific ID or have it automatically generated for them. This ID identifies the Workflow instance and is then used to create the associated Engine DO ID.

The logical starting point for implementation was introspectWorkflowInstance(binding, instanceID), as the instance ID is known in advance. This allows us to generate the Engine DO ID required to identify the engine associated with that Workflow instance.

But often, one part of your application (like an HTTP endpoint) will create a Workflow instance with a randomly generated ID. How can we introspect an instance when we don’t know its ID until after it’s created?

The answer was to use a powerful feature of JavaScript: Proxy objects.

When you use introspectWorkflow(binding), we wrap the Workflow binding in a Proxy. This proxy non-destructively intercepts all calls to the binding, specifically looking for .create() and .createBatch(). When your test triggers a workflow creation, the proxy inspects the call. It captures the instance ID — either one you provided or the random one generated — and immediately sets up the introspection on that ID, applying all the modifications you defined in the modifyAll call. The original creation call then proceeds as normal.

env[workflow] = new Proxy(env[workflow], {
  get(target, prop) {
    if (prop === "create") {
      return new Proxy(target.create, {
        async apply(_fn, _this, [opts = {}]) {

          // 1. Ensure an ID exists 
          const optsWithId = "id" in opts ? opts : { id: crypto.randomUUID(), ...opts };

          // 2. Apply test modifications before creation
          await introspectAndModifyInstance(optsWithId.id);

          // 3. Call the original 'create' method 
          return target.create(optsWithId);
        },
      });
    }

    // Same logic for createBatch()
  }
}

When the await using block from introspectWorkflow() finishes, or the dispose() method is called at the end of the test, the introspector is disposed of, and the proxy is removed, leaving the binding in its original state. It’s a low-impact approach that prioritizes developer experience and long-term maintainability.

Get started with testing Workflows

Ready to add tests to your Workflows? Here’s how to get started:

  1. Update your dependencies: Make sure you are using @cloudflare/vitest-pool-workers version 0.9.0 or newer. Run the following command in your project: npm install @cloudflare/vitest-pool-workers@latest

  2. Configure your test environment: If you’re new to testing on Workers, follow our guide to write your first test.

Start writing tests: Import introspectWorkflowInstance or introspectWorkflow from cloudflare:test in your test files and use the patterns shown in this post to mock, control, and assert on your Workflow’s behavior. Also check out the official API reference.

CHERIoT 1.0 released

Post Syndicated from jzb original https://lwn.net/Articles/1044915/

Version
1.0
of the Capability Hardware Extension to RISC-V for IoT
(CHERIoT) specification has been released. CHERIoT is a
hardware-software system for secure embedded devices, and the
specification provides a full description of the ISA and its intended
use by CHERIoT
RTOS
. David Chisnall has written a blog
post
about the release that explains its significance as well as plans
for CHERIoT 2.0 and beyond:

The last change that we made to the ISA was in December 2024, so we
are confident that this is a stable release that we can support in
hardware for a long time. This specification was implemented by the
1.0 release of CHERIoT Ibex and by CHERIoT Kudu (which has not yet had
an official release). These two implementations demonstrate that the
ISA scales from three-stage single-issue pipelines to six-stage
dual-issue pipelines, roughly the same range of microarchitectures
supported by Arm’s M profile.

We at SCI have the first of our ICENI chips, which use the CHERIoT
Ibex core, on the way back from the fab now and will be scaling up to
mass production in the new year. I am not allowed to speak for other
folks building CHERIoT silicon, but I expect 2026 to be an exciting
year for the CHERIoT project!

Cybercriminals Targeting Payroll Sites

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/cybercriminals-targeting-payroll-sites.html

Microsoft is warning of a scam involving online payroll systems. Criminals use social engineering to steal people’s credentials, and then divert direct deposits into accounts that they control. Sometimes they do other things to make it harder for the victim to realize what is happening.

I feel like this kind of thing is happening everywhere, with everything. As we move more of our personal and professional lives online, we enable criminals to subvert the very systems we rely on.

Домовете за деца – между институционалното наследство и човешкото лице на грижата

Post Syndicated from Евгения Тонева original https://www.toest.bg/domovete-za-detsa-mezhdu-institutsionalnoto-nasledstvo-i-choveshkoto-litse-na-grizhata/

Домовете за деца – между институционалното наследство и човешкото лице на грижата

Едно от най-традиционните български неща е грижата за чуждо дете, сякаш е твое. Преди век и половина това се е наричало храненичество: дете да се отглежда в друго семейство, без да губи връзка със своите родители и роднини. Без законодателство, без формалности – просто грижа. По-късно, когато държавата поема ролята на „по-добрия родител“, възникват домовете за деца, чрез които тази естествена загриженост се институционализира. В опита си да реши по структуриран, стандартизиран начин сериозни социални проблеми, държавата създава нов – как да отгледаш здраво, силно, отговорно и съзнателно дете, без да се свързваш с него по автентичен, човешки начин.

Кратка история на домовете за деца в България 

Първите сиропиталища в страната ни са създадени в началото на ХХ век в подкрепа на децата, останали без родител, без покрив над главата си или без храна в тежките периоди около войните и националните катастрофи. Тези институции са изградени и управлявани изцяло от граждански инициативи, т.нар. благотворителни дружества. В началото на 40-те години в страната има 18 сиропиталища, в които живеят около 1200 крайно нуждаещи се деца.

Скоро след 1944 г. благотворителните дружества са ликвидирани. Съществуващите институции за детска грижа са национализирани и всякакъв официален граждански ангажимент към тяхната дейност става незаконен. След като държавата поема управлението, дейността им е не просто реорганизирана, а започва да се подчинява на нова, различна логика. 

В Решение на Централния съвет за обществени грижи и възпитание на детето към БКП още през 1948 г. се изтъква, че въпросът за оцеляването и отглеждането на децата е приоритетен за народната република и затова „на детето следва да не се гледа вече като на принадлежност и бреме за семействата, а като на бъдещ член на обществото и държавата“ (ако не е упоменато друго, акцентите тук и по-нататък са на авторката), за който последната се ангажира да положи съответните правилни грижи. 

Този въпрос е от особена важност, но не защото детето се разглежда като ценност само̀ по себе си, 

а защото неговото възпитаване има отношение към добруването на обществото, в което от всеки отделен член се очаква да се реализира пълноценно според социалистическата идеология и морал. Аргументите са, на първо място, както обикновено, демографски: повече деца значи повече членове на социалистическото общество. 

Освен въпроса за количеството обаче, стои и този за качеството. Социалистическата идеология и морал предполагат също, че детето може да бъде „бреме“ както за собственото си семейство (ако е родено извън нормата, извънбрачно, с увреждания, още едно гърло за изхранване, но и непокорно, „трудно“ – все неща, които биха попречили на останалите от семейството да са пълноценни членове на обществото), така и за цялото общество (ако порасне като нефункционален, не-полезен възрастен негов член). 

Заимствайки модела, развит със същата цел в Съветския съюз, социалистическата държава се заема да реши чрез „домове“ проблемите при отглеждането на децата, които смята за социално значими. В духа на цитирания по-горе документ, тези институции са добро решение. Те осигуряват място за живот на деца, лишени от адекватни родителски грижи. Но също така помагат на семействата – родителите се освобождават от ежедневните грижи за „трудни деца“ в условията на интензивна индустриализация. При това, както се твърди, в домовете децата получават от държавата професионални грижи, които са по-добри от тези вкъщи.

Видове институции за деца

Изграждането на мрежата от специализирани институции започва с домове за бебета – познатите домове „Майка и дете“, които целят основно намаляване на високата детска смъртност в ранна възраст, поемайки грижата за бебетата вместо бедните и неграмотни техни майки. После – седмични ясли и детски градини (откъдето децата се прибират вкъщи само през почивните дни), домове за деца и юноши, за деца с увреждания (различни видове), общежития и интернати към специализирани учебни заведения. След по-малко от 20 години вече работят над 150 дома с повече от 14 000 деца в тях. 

Най-многобройни са домовете за деца и юноши, в каквито са преобразувани и бившите сиропиталища. В „Ръководство за възпитателна работа в домовете за деца и юноши“ от 1970 г. четем, че това са „държавни възпитателни заведения за деца и юноши от 3- до 19-годишна възраст, на които липсват условия за правилно отглеждане и възпитание в семействата“. Задачата на домовете е подрастващите да получат добри материални условия за живот и „правилно развитие“, в което централно място заема възпитанието, и то „в комунистически дух“. По-конкретно – „любов към ПАРТИЯТА, ПРАВИТЕЛСТВОТО и преданост към СЪВЕТСКИЯ СЪЮЗ“, според същия Правилник (акцентите са на оригинала).

Правилното възпитание се реализира колективно, тъй като се смята, че изграждането на личността е възможно само чрез колектив. 

Всекидневието трябва да се подчинява на строго установен режим и правила, вдъхновени от възгледите на съветския педагог Антон Макаренко. Режимът обхваща всички дейности – учение, труд, почивка и забавления – и изрично цели да се ограничи свободното време, за да се предотврати търсенето на всякакви занимания извън дома и контрола на възпитателите. Така институцията се оказва не просто място за живеене, а изолирана от външния свят система, която работи за изграждане на дисциплинирани и идеологически правилно ориентирани личности. 

Домовете за деца с увреждания поемат грижата за неподлежащите на стандартно възпитание. Децата с по-леки нарушения в развитието се насочват към интернати към специализирани училища, а тези с по-тежки – към институции, изградени на регионален принцип. На родителите, насърчавани активно да настаняват децата си в тях, те са представяни като места, където децата получават медицински и терапевтични грижи, по-подходящи за тяхното състояние в сравнение с грижите в домашна среда. На практика обаче професионализмът на персонала често е формален, а самите домове, намиращи се под управлението на Социалното, а не на Здравното министерство, се намират в малки и отдалечени населени места. 

Изследователи на този тип институции смятат, че те са инструмент за осъществяване на целенасочена политика на изолация: ясен е стремежът за „скриване“ на девиантността, характерен за социалистическата концепция за социална хигиена. 

Чрез физическото изолиране на децата с увреждания държавата поддържа илюзията за общество без „инвалиди“. 

Ежедневието и в тези институции също е стриктно организирано и подчинено на следването на режим, а обитателите им правят всичко заедно, често при пълна липса на лично пространство и вещи. Във все още съществуващите след 2010 г. такива домове, които самата аз съм посещавала по онова време, децата нямаха собствени дрехи – облеклото беше общо.

Децата с увреждания после се превръщат във възрастни с увреждания, за които също са създадени множество институции на същия принцип и със същото предназначение. На всеки, достатъчно смел да се докосне до изкривената, зловеща реалност в тях, препоръчвам наскоро издадения фотоалбум на Антоан Божинов „Излишни“. В него са събрани фотоесета от посещения в домове за деца и възрастни в Северозападна България през 80-те и 90-те години. Сборникът завършва със статия на психиатъра д-р Владимир Сотиров за историята на възникването и проблемите на социалните домове за възрастни хора в страната. Темата е особено интересна в контекста на общественото внимание към „домовете на ужасите“ през 2025 г.

Домът за деца като тотална институция 

Институциите за грижа за деца са замислени и функционират не просто като места, които осигуряват подслон, сигурност, топлина – с каквито асоциираме думата „дом“, – а като технология за управление на социални проблеми. Социалистическата държава се заявява като по-компетентна от родителите да поеме грижата за всяко „трудно“ за отглеждане и възпитание дете. Така тя решава свои идеологически въпроси и „се справя“ – но чрез прикриването им – с големи структурни предизвикателства, като бедността, уязвимостта и уврежданията. Логиката е, че ако страданието е невидимо, то не съществува. 

Това прикриване се представя като акт на грижа, но под повърхността се трупат нерешени проблеми, а броят на домовете и децата в тях расте. Качеството на „грижата“ също толкова естествено намалява. Фокусът, доколкото изобщо е бил другаде, се измества върху спазването на режима, контрола, отчетността, а в крайна сметка – върху управлението на самите институции, финансирането на които става все по-оскъдно. 

„Тотална институция“ е концепция, развита от канадския социолог Ървинг Гофман през 60-те години въз основа на изследователската му работа в психиатрии. 

Гофман описва един тип затворена система, в която животът на обитателите е регулиран от установен режим, а едни и същи елементи от ежедневието се изпълняват от всички заедно, в група, в рамките на едни и същи пространства и под надзора на персонала. Това създава илюзията, че хората, настанени в такива заведения, са абсолютно еднакви. При нормални обстоятелства хората влизат в различни социални роли, казва Гофман, и си взаимодействат с другите по различни начини вкъщи, на работа, в градския транспорт, в киното, но в институциите начинът на живот не предполага това. Затова и институциите вредят.

Домовете за деца в България от времето на социализма напълно отговарят на характеристиките на тоталната институция.

Всъщност те са създадени, за да бъдат именно това. Границата между индивидуалното и колективното в тях е почти напълно заличена в името на „удобството“ много деца да бъдат едновременно и ефективно обгрижвани, възпитавани, дисциплинирани. При това те са изолирани от останалия свят, така че както неестественото ежедневие, така и проблемите, довели до попадането им в домовете, остават невидими. 

Помислете си за следната сцена, позната на поколения българи: 30 малки деца седят на гърнета в детската градина – заедно, в едно помещение, в определен момент от деня. Това е съвършено неестествена ситуация от гледна точка на физиологията, но напълно нормална от гледна точка на удобството – трябва да е „подредено“, така че двама възрастни да са в състояние да се справят с всички тези деца. Сега си помислете, че докато за повечето от нас това е било просто един неприятен момент от деня в детската градина, ежедневието на децата в домовете е низ само от такива моменти.

Тоталните институции са страшни не само заради фиксацията върху контрола и прикриването на социалните проблеми, а най-вече защото неизбежно дехуманизират както обитателите, така и персонала си. 

В тях хората са лишени от човешко лице, от индивидуалност и автономия. Те са просто части от един механизъм, който работи основно по поддържането на собственото си функциониране. В дома детето престава да бъде личност със свои нужди и емоции и се превръща във „възпитаник“, а възпитателят – в съблюдател на правила. Това положение притъпява емпатията, която при други обстоятелства би възникнала спонтанно, и обезличаването става норма.

Обезличаването и изолацията водят до стигма. Обществото започва да гледа на децата от домовете като на „други“, „различни“, „повредени“, „опасни“, без да се задълбочава в историите им и да ги третира като отделни човешки същества. Самите домове се превръщат не само в отражение на страха от „другото“, намиращото се „извън нормата“, но и го възпроизвеждат, като със самото си съществуване затвърждават нагласата, че социалните проблеми са решими чрез изолация, строг режим и дисциплина. 

15 години след обещанието за деинституционализация

В статията си за реформата на домовете разказах за деинституционализацията, която трябваше да гарантира, че всяко дете ще бъде отглеждано в среда, максимално близка до семейната. Днес, 15 години след обещанието за тази реформа, в навечерието на изтичането на срока за осъществяването ѝ, почти всяка четвърта от уж новите социални услуги за грижа се намира в сграда, в която в миналото е имало дом. 30 от тях – за над 350 деца – се намират в села или малки градове с население под 5000 души. Други 25 услуги – за още 300 деца – са създадени в такива населени места като част от плана за деинституционализация. При общ капацитет на всички услуги приблизително 3400 места това означава, че 

20% от местата за настаняване на деца в малките групови домове, с които разполага държавата в момента, са в села и градчета със затихващи функции. 


За общинските администрации, които управляват малките групови домове, те са актив: социални дейности за отчитане и възможности за осигуряване на заетост, финансирани при това от държавния бюджет. За децата от близо и далеч, които се озовават там обаче, те носят предимно познатите от миналото изолация и стигматизиране.

Натрупаните през последните няколко години критични анализи на резултатите от реформата насочват вниманието към факта, че 

дори и в малките групови домове, които не са в сградите на стари институции и/или в отдалечени населени места, няма сигурна семейна среда. 

Въпреки значително подобрените материални условия и претенцията, заявена в официалното наименование на малките групови домове – „центрове за настаняване от семеен тип“, – нагласите и отношенията в тях следват институционална логика, а не логиката на правата. Обитателите са твърде много, за да получават индивидуално внимание, а персоналът се състои предимно от недостатъчно квалифицирани и недобре заплатени служители, което предполага възпроизвеждане на старите модели. В ежедневието всичко се върти около реда и правилата. Децата разполагат с малко време извън центровете и с нищожно количество собствени пари и вещи, което допълнително засилва социалната им изолация, кара ги да се срамуват от връстниците си и създава рискове да станат жертви или извършители на престъпления. 

В много от новите малки домове за деца с увреждания пък институционалните практики, които противоречат на принципите за зачитане на човешкото достойнство, продължават да са ежедневие. Режимът остава еднакъв за всички, децата нямат право на избор в ежедневието си, личните им предпочитания не са от значение, поведението им се контролира с наказания, а понякога и с медикаменти. 

На този фон

най-големият проблем си остава липсата на осезаема промяна в нагласите към държавната грижа и ползвателите ѝ. 

Именно от това произтичат най-сериозните негативи за децата. Стари или нови, домовете продължават да бъдат „затворените системи“ от миналото, асоцииращи се с нелицеприятни тайни и социални проблеми, за които хората предпочитат да не знаят; на децата се гледа с подозрение и резерви, а често те са и откровено дискриминирани. Донякъде парадоксално, тези негативни нагласи засягат дори децата, които растат в приемна грижа. 

Как системата да престане да произвежда аутсайдери 

Всяка година около 200 навършващи пълнолетие млади хора в България напускат малките групови домове и приемната грижа. Началото на самостоятелния им живот рядко е леко. Причината е не само че държавата не им осигурява нужната подкрепа след излизането от системата. Помощта, която се предлага, и то съвсем отскоро, се изчерпва с минимални средства за първите три месеца и понякога с логистична подкрепа за настаняване в общинско жилище или за намиране на някаква първа работа. 

Истинският проблем е, че децата не са подготвени за реалността извън системата за грижа и носят травми от живота си в нея. 

В домовете те порастват не защитени, а уязвими. Без възможности да развият социалните умения, които се формират естествено чрез доверие, право на избор и лична отговорност, те се оказват изложени на рискове навън, в истинския свят. В приемната грижа това не е така. Но и там най-често порасналите деца застават на прага на самостоятелния си живот без капка вяра във възможностите и потенциала си, без амбиции, без мечти. Стигмата ги следва, където и да отидат.

Ако искаме системата за грижа да изгражда млади хора, уверени в собствената си стойност, способни да развиват талантите си и мотивирани да работят здраво за бъдещето си, тя трябва преди всичко да се освободи от институционалната логика и нагласи, които все още я движат. Да престане да се грижи приоритетно за собственото си функциониране и да се отвори към света навън, за да позволи децата да бъдат видени и третирани като истински хора, а не като проблеми, които трябва да се държат под контрол.

Celebrating young tech creators: Coolest Projects 2025 and what’s next in 2026

Post Syndicated from Helen Gardner original https://www.raspberrypi.org/blog/celebrating-young-tech-creators-coolest-projects-2025-and-whats-next-in-2026/

Coolest Projects is all about celebrating young digital creators and the brilliant things they make with technology. This year, we’ve seen just how much taking part can boost young people’s confidence, creativity, and sense of belonging. Today, we’re sharing the impact of Coolest Projects 2025 and looking ahead to what’s next for 2026.

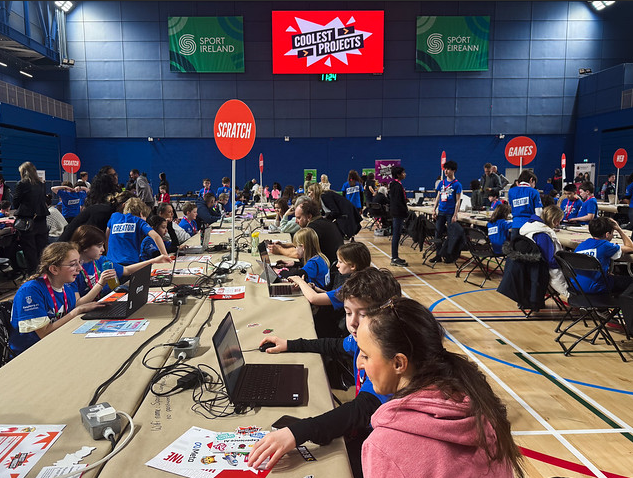
Young creators at the Coolest Projects Ireland 2025 event.

Highlights from Coolest Projects 2025

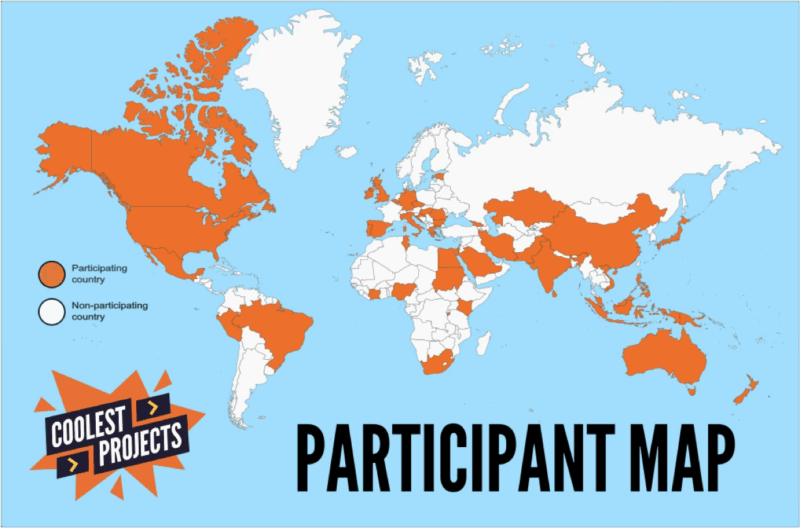
More young people than ever took part in 2025, with 11,980 young people from 41 countries joining the Coolest Projects global online showcase, a 57% increase from last year. We also hosted a livestream celebrating all participants and announcing the judges’ favourites, which has been watched by over 2,000 people. Plus, we expanded our in-person events, including bringing Coolest Projects back to the USA and running our very first in-person event in India.

This year saw significant growth in in-person events, with a record number of young people sharing their creations face-to-face. Across the UK and Ireland, more than 200 young people showcased their projects to judges, families, and peers. Attendance at the UK event grew significantly compared to 2024, reflecting the strong enthusiasm for digital making, while the Ireland event continued to attract a dedicated community of young creators. This enthusiasm shows how much young people value being part of a creative, supportive community that helps them share ideas and develop their skills.

The Coolest Projects 2025 participant map.

We were equally delighted to run Coolest Projects USA again, where young people embraced the chance to connect, share their work, and draw inspiration from one another. We also saw strong interest in the new AI category, with notable uptake at the UK and US events.

Participation by girls in the online showcase kept growing in 2025: 51% of entrants identified as female, up from 47% last year. We’re excited to build on this momentum and inspire even more girls to share their creations in 2026. We’ll continue encouraging participation by girls across all categories and broaden local promotion, especially where new in-person events are launching, to help maintain gender balance.

Online showcase: Confidence, skills, and inspiration

To understand Coolest Projects’ impact, we gathered survey and interview feedback from young creators, mentors, and event attendees across both the online showcase and in-person events. 

This year’s online surveys and interviews indicate that Coolest Projects continues to be a powerful driver of confidence and skills:

  • 72% of young people and 100% of mentors agreed that participating increased confidence in coding and digital making
  • 89% of young people reported improved coding and digital making skills
  • 83% of young people (and 100% of mentors) said they felt inspired to continue with computing and digital making after taking part

Young people and mentors told us that the online gallery plays a crucial role in sparking ideas and motivation:

“Kids definitely were excited in knowing their project might be seen by other kids around the world and displayed publicly online, so it’s truly a way for them to feel recognised. It definitely motivated them too.” – Mentor, South Africa

Coolest Projects truly offers a global setting like no other, giving young people the chance to see ideas from across the world and feel part of an inspiring international community.

In-person events: community and belonging

Creators told us how special it felt to be surrounded by peers who love making with technology. They valued sharing their projects, meeting like-minded people, and getting ideas from others:

“I think it’s really interesting seeing a lot of other children that understand programming and want to get better at it.” – Young creator, Coolest Projects USA

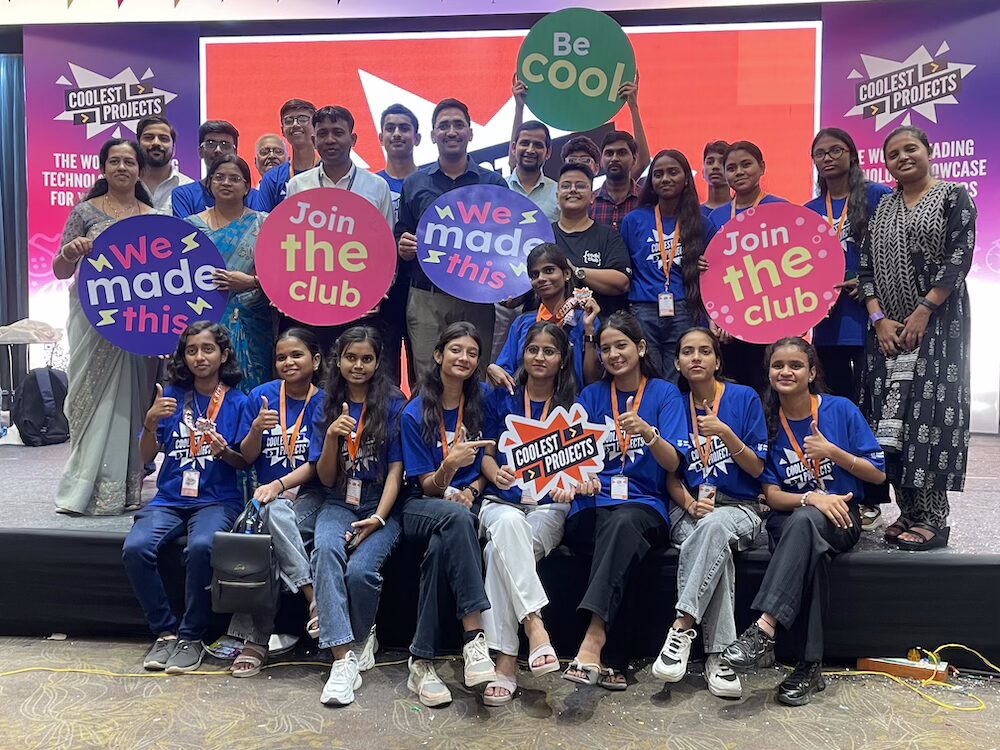
Young creators at the Coolest Projects India 2025 event.

Survey data echoes this: 74% of young people said Coolest Projects helped them feel they belong in computing. Many also highlighted the wider skills they developed, from problem solving and creativity to communication and teamwork:

“We [my friends and I] thought it was a really great opportunity and idea to make a project that we could all work on together and it’s been really awesome getting to know these girls and working together, fixing whatever code that we made wrong, debugging, you know…. We’d come together once a week to work on this project. So, I honestly got to learn a lot from them, watching them and how they code because they’re a little more advanced than I am. But, you know, that just means I get to learn more. So, you get to learn skills and support each other. It’s been awesome…”  – Young creator, Coolest Projects USA

Young people returning for another year described how they stretched themselves, from advanced Scratch techniques to experimenting with AI and robotics. They also said hands-on project work is better than passive learning every time.

“…It’s the journey on which I go through to create the robot. And through that journey, I seem to learn much more than say if I were to watch a YouTube video and not do anything practical with it. I learn much more if I physically get hands-on with robotics encoding.” – Young creator, Coolest Projects UK

Alongside the projects on show, young people loved the interactive activities at events (with shout outs for VR and our escape room in the UK), and appreciated the friendly, approachable judges and smooth event setup. A new group registration system also made it much easier for mentors to enter multiple projects.

Dates for Coolest Projects 2026

We’re thrilled that so many young people around the world took part this year, and we can’t wait to welcome even more creators in 2026.

“Make it [the event] bigger so more people can come.” – Young creator, Coolest Projects USA

The Coolest Projects online showcase is open to any young person up to age 18, anywhere in the world. Registration will open on 14 January 2026. We’ll host a celebratory livestream on 24 June 2026.

Coolest Projects in-person events will also be popping up around the world. In-person events are open to everyone up to age 18 in the host country. Family and friends are very welcome to come along too. 

Save the date for:

  • Coolest Projects Belgium, 14 March
  • Coolest Projects Japan, 28 March
  • Coolest Projects USA Minnesota, 11 April
  • Coolest Projects USA Georgia, 2 May
  • Coolest Projects UK, 16 May
  • Coolest Projects Sudan (held in Egypt), 12 August
  • Coolest Projects Nigeria, 29 August

More dates coming soon for:

  • Coolest Projects Canada 
  • Coolest Projects India
  • Coolest Projects Indonesia
  • Coolest Projects Ireland
  • Coolest Projects Malaysia
  • Coolest Projects South Africa
  • Coolest Projects Sri Lanka

Want to be first to know when more dates are confirmed? Sign up to our newsletter and keep an eye on the Coolest Projects website for announcements.

Get involved

It’s never too early to start making and saving your digital projects for next year’s showcase. Whether you’re into AI, games, web, hardware, or Scratch, there’s a place for your ideas at Coolest Projects. 

Start by:

We can’t wait to see what the world’s young tech creators will make next!

The post Celebrating young tech creators: Coolest Projects 2025 and what’s next in 2026 appeared first on Raspberry Pi Foundation.

Creating a Community-Driven Zabbix Book

Post Syndicated from Zane Lasmane original https://blog.zabbix.com/creating-a-community-driven-zabbix-book/31688/

At the recent Zabbix Summit community meeting, participants gathered to discuss an exciting initiative – the creation of the first-ever community-driven Zabbix book. While several books about Zabbix have been published in the past (often written by individual authors over a decade ago), this project marks a new milestone. For the first time, Zabbix community members from around the world are coming together to co-author a book, share their expertise, and tell the Zabbix story from many perspectives.

What is the Zabbix Book?

The project, hosted at thezabbixbook.com, is an open, collaborative effort led by Nathan Liefting and Patrik Uytterhoeven from Opensource ICT Solutions B.V. The goal is to create a community-built guide to Zabbix, written by users, for users. As Zabbix trainers, Patrik and Nathan have both been long-time (don’t want to say old) contributors to the Zabbix community, authoring multiple books and blog posts.

The Zabbix Book will cover topics ranging from cloud templates and infrastructure monitoring to host triggers, Zabbix internals, SNMP, low-level discovery, multi-factor authentication, and much more. Each contributor can choose a specific chapter or topic that matches their expertise, making it a truly collective and flexible effort.

The content is managed on GitHub, written in Markdown, and follows open contribution principles. The aim is to complete the main foundation of the book alongside the release of Zabbix 8.0 LTS (expected in 2026, Q1/Q2), with an update to include new 8.0 features approximately a month later.

Why write a Zabbix Book when documentation exists?

While the official Zabbix documentation remains the primary source for technical accuracy, the Zabbix Book serves as an alternative and more narrative approach to learning, created by everyday Zabbix users. It’s designed to introduce new users to Zabbix through practical examples, real-world use cases, and community wisdom – making it easier for newcomers to connect the dots.

How the community works together

During the Summit breakout session, the group discussed:

• The current project status and foundational setup
• How contributions are managed — commits, rules, and legal aspects
• Missing topics and a call for more writers, editors, and translators
• Ideas for practical information and real-world examples (like JMX, SNMP, etc.)
• Donations and funding goals, including ideas for supporting open-source projects, good causes, or new Zabbix community features

The project embraces an open, democratic spirit – anyone can contribute, vote, or help improve the book’s structure, content, and readability. The Zabbix Book is created by the Monitoring Penmasters Foundation, which was created in order to make it a real community project – all the intellectual rights belong to the foundation itself, and when revenue is created there will be a  vote on where to donate the money.

Currently, the Monitoring Penmasters foundation consists of Patrik, Nathan, and Zabbix CEO and Founder Alexei Vladishev, who is involved in the book’s review and has agreed to contribute to some parts of the book while allocating design resources from Zabbix itself.

The project has also gotten a big assist from Brian van Baekel of Opensource ICT Solutions, a dedicated community member and certified Zabbix trainer who has given his fair share of presentations and written extensively about Zabbix and its capabilities.

Get involved

If you’d like to contribute, share your expertise, or simply follow the book’s progress, visit thezabbixbook.com to explore the current chapters and learn how to join the project. The project’s digital chapters are available to everyone, and while the writing and printing are still in progress, we hope to see finalized online and printed versions in spring 2026.

It’s also worth remembering that even though the book is free to download and use, the creators do have costs and financial contributions are welcome – you can chip in here.

Together, we’re not just writing a book — we’re writing a piece of Zabbix community history!

The post Creating a Community-Driven Zabbix Book appeared first on Zabbix Blog.

The collective thoughts of the interwebz