Interest in a very sensitive digital topic has been gaining momentum in recent weeks – the so-called “chat control” – a draft EU regulation under which every message we send, even through encrypted applications, would be scanned for child sexual abuse materials (the so-called CSAM).
I will make a retrospective and explain the technical problems, but before that I must state that the political party I represent holds the position that invasive measures against private correspondence, which create conditions for mass surveillance, must not be implemented. Therefore, the proposal – both in its original form and in the version seen by the Danish presidency – is unacceptable.
Even without the provisions concerning encrypted applications, the regulation makes serious steps toward improving the effectiveness of combating the spread of CSAM. Thus, at the upcoming Council of the EU meeting in the fall, the hot issue will be precisely encrypted applications – on the rest there is rather consensus, since it is indisputable that more serious and effective counteraction against such crimes is needed. Therefore, the remaining provisions of the regulation should be supported.
Initially, this proposal included the possibility of sending images centrally to a European body for scanning. This was met with strong disapproval, since in practice it eliminates end-to-end encryption – if every message containing a photo or a link is sent somewhere, encryption is effectively nullified.
Therefore, under a previous Council presidency, there was a working proposal to limit this measure only to already known content (CSAM) and for scanning to be carried out only on the device, before encryption, without sending anything anywhere. At first glance, this sounded more reasonable, as it moved the proposal away from mass surveillance. It even seemed, at first glance, that artificial intelligence could be applied directly on the device. At the time, I made such an assumption, with the caveat that careful analysis was needed.
But once such careful analysis is done, it becomes clear that this approach is both dangerous and not particularly useful for achieving the goal. I will list a few details:
Organized crime groups involved in the distribution of CSAM would simply start using their own applications, which, thanks to another EU regulation (the DMA), they would be able to install on their phones without complying with the new requirements. In other words, the protection of ordinary people’s private correspondence would be weakened and risks of mass surveillance and abuse would be created, while criminal groups would bypass it.
At present, there is no technology capable of implementing the Danish presidency’s and the Commission’s vision in a workable way. Algorithms for so-called perceptual hashing (or fuzzy hashing) were not designed to withstand malicious modifications – with small visual effects or transformations of images, they will go undetected. Likewise, both these algorithms and AI models that would work on end devices produce false positives, which risks flooding law enforcement with entirely legal photos. For such a technology to be introduced by regulation, it must meet all these (and other) challenges – we cannot allow proprietary, experimental technologies to become part of legal frameworks, especially when fundamental constitutional rights are at stake.
The technology, if one day a sufficiently good one is developed, must be open source, and if it uses AI – the model must also be open, with a very clear and transparent process for auditing the training data. The perceptual hashing algorithm should be resistant to malicious image alterations, because otherwise it’s pointless to even try to impose such techniques. Furthermore, the central database must be subject to very strict procedures for submission and verification of content, because otherwise a member state with a low level of rule of law could submit other content, including political content, that it wishes to monitor or censor. Last summer’s example in Bulgaria with the takedown of the satirical website New Beginning (the party of the strongest local local oligarch) is just an indication of how such abuse could happen. Apart from the initial takedown, the website also appeared on lists by cybersecurity companies as “adult content” and was blocked in networks where software by those companies was installed.
These are only part of the arguments why the proposal is ill-conceived. A much longer debate on the issue is needed, as well as many more academic studies researching and developing technological readiness for such approaches. The good news is that many countries are still hesitant, among them Germany, and thus there is no majority in the Council, while the mandate of the European Parliament is against this type of invasive changes.
When there is legitimate criticism of the EU, it is that such types of regulation are possible. But the answer to this criticism is that member states evidently value guarantees for personal freedom, and that within a serious debate across the entire European Union, Orwellian measures can be stopped and working solutions can be found instead of well-sounding but nonfunctional technological regulations.
One of Cloudflare’s big focus areas is making the Internet faster for end users. Part of the way we do that is by looking at the “big rocks” or bottlenecks that might be slowing things down — particularly processes on the critical path. When we recently turned our attention to our privacy proxy product, we found a big opportunity for improvement.
What is our privacy proxy product? These proxies let users browse the web without exposing their personal information to the websites they’re visiting. Cloudflare runs infrastructure for privacy proxies like Apple’s Private Relay and Microsoft’s Edge Secure Network.
Like any secure infrastructure, we make sure that users authenticate to these privacy proxies before we open up a connection to the website they’re visiting. In order to do this in a privacy-preserving way (so that Cloudflare collects the least possible information about end-users) we use an open Internet standard – Privacy Pass – to issue tokens that authenticate to our proxy service.
Every time a user visits a website via our Privacy Proxy, we check the validity of the Privacy Pass token which is included in the Proxy-Authorization header in their request. Before we cryptographically validate a user’s token, we check if this token has already been spent. If the token is unspent, we let the user request through. Otherwise, it’s a “double-spend”. From an access control perspective, double-spends are indicative of a problem. From a privacy perspective, double-spends can reduce the anonymity set and privacy characteristics. From a performance perspective, our privacy proxies see millions of requests per second – and any time spent authenticating delays people from accessing sites – so the check needs to be fast. Let’s see how we reduced the latency of these double-spend checks from ~40 ms to <1 ms.
How did we discover the issue?
We use a tracing platform, Jaeger. It lets us see which paths our code took and how long functions took to run. When we looked into these traces, we saw latencies of ~ 40 ms. It was a good lead, but it alone was not enough to conclude it was an issue. The reason was we only sample a small percentage of our traces, so what we saw was not the whole picture. We needed to look at more data. We could’ve increased how many traces we sampled, but traces are large and heavy for our systems to process. Metrics are a lighter weight solution. We added metrics to get data on all double-spend checks.
The lines in this graph are median latencies we saw for the slowest privacy proxies around the world. The metrics data gave us confidence that it was a problem affecting a large portion of requests… assuming that ~ 45 ms was longer than expected. But, was it expected? What numbers did we expect?
The expected latency
To understand what times are reasonable to expect, let’s go into detail on what makes up a “double-spend check”. When we do a double-spend check, we ask a backing data store if a Privacy Pass token exists. The data store we use is memcached. We have many memcached instances running on servers around the world, so which server do we ask? For this, we use mcrouter. Instead of figuring out which memcached server to ask, we give our request to mcrouter, and it will handle choosing a good memcached server to use. We looked at the median time it took for mcrouter to process our request. This graph shows the average latencies per server over time. There are spikes, but most of the time the latency is < 1 ms.
By this point, we were confident that double-spend check latencies were longer than expected everywhere, and we started looking for the root cause.
How did we investigate the issue?
We took inspiration from the scientific method. We analyzed our code, created theories for why sections of code caused latency, and used data to reject those theories. For any remaining theories, we implemented fixes and tested if they worked.
Let’s look at the code. At a high level, the double-spend checking logic is:
Get a connection, which can be broken down into:
Send a memcached version command. This serves as a health check for whether the connection is still good to send data on.
If the connection is still good, acquire it. Otherwise, establish a new connection.
Send a memcached get command on the connection.
Let’s go through the theories we had for each step listed above.
Theory 1: health check takes long
We measured the health check primarily as a sanity check. The version command is simple and fast to process, so it should not take long. And we remained sane. The median latency was < 1 ms.
Theory 2: waiting to get a connection
To understand why we may need to wait to get a connection, let’s go into more detail on how we get a connection. In our code, we use a connection pool. The pool is a set of ready-to-go connections to mcrouter. The benefit of having a pool is that we do not have to pay the overhead of establishing a connection every time we want to make a request. Pools have a size limit, though. Our limit was 20 per server, and this is where a potential problem lies. Imagine we have a server that processes 5,000 requests every second, and requests stay for 45 ms. We can use something called Little’s Law to estimate the average number of requests in our system: 5000 x 0.045 = 225. Due to our pool size limits, we can only have 20 connections at a time, so we can only process 20 requests at any point in time. That means 205 requests are just waiting! When we do a double-spend check, maybe we’re waiting ~ 40 ms to get a connection?
We looked at the metrics of many different servers. No matter what the requests per second was, the latency was consistently ~ 40 ms, disproving the theory. For example, this graph shows data from a server that saw a maximum of 20 requests per second. It shows a histogram over time, and the large majority of requests fall in the 40 – 50 ms bucket.
Theory 3: delays in Nagle’s algorithm and delayed acks
We decided to chat with Gemini, giving it the observations we had so far. It suggested many things, but the most interesting was to check if TCP_NODELAY was set. If we had set this option in our code, it would’ve disabled something called Nagle’s algorithm. Nagle’s algorithm itself was not a problem, but when enabled alongside another feature, delayed ACKs, latencies could creep in. To explain why, let’s go through an analogy.
Suppose we run a group chat app. Normally, people type a full thought and send it in one message. But, we have a friend who sends one word at a time: “Hi”. Send. “how”. Send. “are”. Send. “you”. Send. That’s a lot of notifications. Nagle’s algorithm aims to prevent this. Nagle says that if the friend wants to send one short message, that’s fine, but it only lets them do it once per turn. When they try to send more single words right after, Nagle will save the words in a draft message. Once the draft message hits a certain length, Nagle sends. But what if the draft message never hits that length? To manage this, delayed ACKs initiates a 40 ms timer whenever the friend sends a message. If the app gets no further input before the timer ends, the message is sent to the group.
I took a closer look at the code, both Cloudflare authored code and code from dependencies we rely on. We depended on the memcache-async crate for implementing the code that lets us send memcache commands. Here is the code for sending a memcached version command:
Nothing out of the ordinary. Then, we looked inside the get function.
let writer = self.io.get_mut();
writer.write_all(b"get ").await?;
writer.write_all(key.as_ref()).await?;
writer.write_all(b"\r\n").await?;
writer.flush().await?;
In our code, we set io as a TcpStream, meaning that each write_all call resulted in sending a message. With Nagle’s algorithm enabled, the data flow looked like this:
Oof. We tried to send all three small messages, but after we sent the “get “, the kernel put the token and \r\n in a buffer and started waiting. When mcrouter got the “get “, it could not do anything because it did not have the full command. So, it waited 40 ms. Then, it sent an ACK in response. We got the ACK, and sent the rest of the command in the buffer. mcrouter got the rest of the command, processed it, and returned a response telling us if the token exists. What would the data flow look like with Nagle’s algorithm disabled?
We would send all three small messages. mcrouter would have the full command, and return a response immediately. No waiting, whatsoever.
Why 40 ms?
Our Linux servers have minimum bounds for the delay. Here is a snippet of Linux source code that defines those bounds.
#if HZ >= 100
#define TCP_DELACK_MIN	((unsigned)(HZ/25))	/* minimal time to delay before sending an ACK */
#define TCP_ATO_MIN	((unsigned)(HZ/25))
#else
#define TCP_DELACK_MIN	4U
#define TCP_ATO_MIN	4U
#endif
The comment tells us that TCP_DELACK_MIN is the minimum time delayed ACKs will wait before sending an ACK. We spent some time digging through Cloudflare’s custom kernel settings and found this:
CONFIG_HZ=1000
CONFIG_HZ eventually propagates to HZ and results in a 40 ms delay. That’s where the number comes from!
The fix
We were sending three separate messages for a single command when we only needed to send one. We captured what a get command looked like in Wireshark to verify we were sending three separate messages. (We captured this locally on MacOS. Interestingly, we got an ACK for every message.)
The fix was to use BufWriter<TcpStream> so that write_all would buffer the small messages in a user-space memory buffer, and flush would send the entire memcached command in one message. The Wireshark capture looked much cleaner.
Conclusion
After deploying the fix to production, we saw the median double-spend check latency drop to expected values everywhere.
Our investigation followed a systematic, data-driven approach. We began by using observability tools to confirm the problem’s scale. From there, we formed testable hypotheses and used data to systematically disprove them. This process ultimately led us to a subtle interaction between Nagle’s algorithm and delayed ACKs, caused by how we made use of a third-party dependency.
Ultimately, our mission is to help build a better Internet. Every millisecond saved contributes to a faster and more seamless, private browsing experience for end users. We’re excited to have this rolled out and excited to continue to chase further performance improvements!
The current state of digital identity is a mess. Your personal information is scattered across hundreds of locations: social media companies, IoT companies, government agencies, websites you have accounts on, and data brokers you’ve never heard of. These entities collect, store, and trade your data, often without your knowledge or consent. It’s both redundant and inconsistent. You have hundreds, maybe thousands, of fragmented digital profiles that often contain contradictory or logically impossible information. Each serves its own purpose, yet there is no central override and control to serve you—as the identity owner.
We’re used to the massive security failures resulting from all of this data under the control of so many different entities. Years of privacy breaches have resulted in a multitude of laws—in US states, in the EU, elsewhere—and calls for even more stringent protections. But while these laws attempt to protect data confidentiality, there is nothing to protect data integrity.
In this context, data integrity refers to its accuracy, consistency, and reliability…throughout its lifecycle. It means ensuring that data is not only accurately recorded but also remains logically consistent across systems, is up-to-date, and can be verified as authentic. When data lacks integrity, it can contain contradictions, errors, or outdated information—problems that can have serious real-world consequences.
Without data integrity, someone could classify you as a teenager while simultaneously attributing to you three teenage children: a biological impossibility. What’s worse, you have no visibility into the data profiles assigned to your identity, no mechanism to correct errors, and no authoritative way to update your information across all platforms where it resides.
Integrity breaches don’t get the same attention that confidentiality breaches do, but the picture isn’t pretty. A 2017 write-up in The Atlantic found error rates exceeding 50% in some categories of personal information. A 2019 audit of data brokers found at least 40% of data broker sourced user attributes are “not at all” accurate. In 2022, the Consumer Financial Protection Bureau documentedthousands of cases where consumers were denied housing, employment, or financial services based on logically impossible data combinations in their profiles. Similarly, the National Consumer Law Center report called “Digital Denials” showed inaccuracies in tenant screening data that blocked people from housing.
And integrity breaches can have significant effects on our lives. In one 2024 British case, two companies blamed each other for the faulty debt information that caused catastrophic financial consequences for an innocent victim. Breonna Taylor was killed in 2020 during a police raid on her apartment in Louisville, Kentucky, when officers executed a “no-knock” warrant on the wrong house based on bad data. They had faulty intelligence connecting her address to a suspect who actually lived elsewhere.
In some instances, we have rights to view our data, and in others, rights to correct it, but these sorts of solutions have only limited value. When journalist Julia Angwin attempted to correct her information across major data brokers for her book Dragnet Nation, she found that even after submitting corrections through official channels, a significant number of errors reappeared within six months.
In some instances, we have the right to delete our data, but—again—this only has limited value. Some data processing is legally required, and some is necessary for services we truly want and need.
Our focus needs to shift from the binary choice of either concealing our data entirely or surrendering all control over it. Instead, we need solutions that prioritize integrity in ways that balance privacy with the benefits of data sharing.
It’s not as if we haven’t made progress in better ways to manage online identity. Over the years, numerous trustworthy systems have been developed that could solve many of these problems. For example, imagine digital verification that works like a locked mobile phone—it works when you’re the one who can unlock and use it, but not if someone else grabs it from you. Or consider a storage device that holds all your credentials, like your driver’s license, professional certifications, and healthcare information, and lets you selectively share one without giving away everything at once. Imagine being able to share just a single cell in a table or a specific field in a file. These technologies already exist, and they could let you securely prove specific facts about yourself without surrendering control of your whole identity. This isn’t just theoretically better than traditional usernames and passwords; the technologies represent a fundamental shift in how we think about digital trust and verification.
Standards to do all these things emerged during the Web 2.0 era. We mostly haven’t used them because platform companies have been more interested in building barriers around user data and identity. They’ve used control of user identity as a key to market dominance and monetization. They’ve treated data as a corporate asset, and resisted open standards that would democratize data ownership and access. Closed, proprietary systems have better served their purposes.
There is another way. The Solid protocol, invented by Sir Tim Berners-Lee, represents a radical reimagining of how data operates online. Solid stands for “SOcial LInked Data.” At its core, it decouples data from applications by storing personal information in user-controlled “data wallets”: secure, personal data stores that users can host anywhere they choose. Applications can access specific data within these wallets, but users maintain ownership and control.
Solid is more than distributed data storage. This architecture inverts the current data ownership model. Instead of companies owning user data, users maintain a single source of truth for their personal information. It integrates and extends all those established identity standards and technologies mentioned earlier, and forms a comprehensive stack that places personal identity at the architectural center.
This identity-first paradigm means that every digital interaction begins with the authenticated individual who maintains control over their data. Applications become interchangeable views into user-owned data, rather than data silos themselves. This enables unprecedented interoperability, as services can securely access precisely the information they need while respecting user-defined boundaries.
Solid ensures that user intentions are transparently expressed and reliably enforced across the entire ecosystem. Instead of each application implementing its own custom authorization logic and access controls, Solid establishes a standardized declarative approach where permissions are explicitly defined through control lists or policies attached to resources. Users can specify who has access to what data with granular precision, using simple statements like “Alice can read this document” or “Bob can write to this folder.” These permission rules remain consistent, regardless of which application is accessing the data, eliminating the fragmentation and unpredictability of traditional authorization systems.
This architectural shift decouples applications from data infrastructure. Unlike Web 2.0 platforms like Facebook, which require massive back-end systems to store, process, and monetize user data, Solid applications can be lightweight and focused solely on functionality. Developers no longer need to build and maintain extensive data storage systems, surveillance infrastructure, or analytics pipelines. Instead, they can build specialized tools that request access to specific data in users’ wallets, with the heavy lifting of data storage and access control handled by the protocol itself.
Let’s take healthcare as an example. The current system forces patients to spread pieces of their medical history across countless proprietary databases controlled by insurance companies, hospital networks, and electronic health record vendors. Patients frustratingly become a patchwork rather than a person, because they often can’t access their own complete medical history, let alone correct mistakes. Meanwhile, those third-party databases suffer regular breaches. The Solid protocol enables a fundamentally different approach. Patients maintain their own comprehensive medical record, with data cryptographically signed by trusted providers, in their own data wallet. When visiting a new healthcare provider, patients can arrive with their complete, verifiable medical history rather than starting from zero or waiting for bureaucratic record transfers.
When a patient needs to see a specialist, they can grant temporary, specific access to relevant portions of their medical history. For example, a patient referred to a cardiologist could share only cardiac-related records and essential background information. Or, on the flip side, the patient can share new and rich sources of related data to the specialist, like health and nutrition data. The specialist, in turn, can add their findings and treatment recommendations directly to the patient’s wallet, with a cryptographic signature verifying medical credentials. This process eliminates dangerous information gaps while ensuring that patients maintain an appropriate role in who sees what about them and why.
When a patient—doctor relationship ends, the patient retains all records generated during that relationship—unlike today’s system where changing providers often means losing access to one’s historical records. The departing doctor’s signed contributions remain verifiable parts of the medical history, but they no longer have direct access to the patient’s wallet without explicit permission.
For insurance claims, patients can provide temporary, auditable access to specific information needed for processing—no more and no less. Insurance companies receive verified data directly relevant to claims but should not be expected to have uncontrolled hidden comprehensive profiles or retain information longer than safe under privacy regulations. This approach dramatically reduces unauthorized data use, risk of breaches (privacy and integrity), and administrative costs.
Perhaps most transformatively, this architecture enables patients to selectively participate in medical research while maintaining privacy. They could contribute anonymized or personalized data to studies matching their interests or conditions, with granular control over what information is shared and for how long. Researchers could gain access to larger, more diverse datasets while participants would maintain control over their information—creating a proper ethical model for advancing medical knowledge.
The implications extend far beyond healthcare. In financial services, customers could maintain verified transaction histories and creditworthiness credentials independently of credit bureaus. In education, students could collect verified credentials and portfolios that they truly own rather than relying on institutions’ siloed records. In employment, workers could maintain portable professional histories with verified credentials from past employers. In each case, Solid enables individuals to be the masters of their own data while allowing verification and selective sharing.
The economics of Web 2.0 pushed us toward centralized platforms and surveillance capitalism, but there has always been a better way. Solid brings different pieces together into a cohesive whole that enables the identity-first architecture we should have had all along. The protocol doesn’t just solve technical problems; it corrects the fundamental misalignment of incentives that has made the modern web increasingly hostile to both users and developers.
As we look to a future of increased digitization across all sectors of society, the need for this architectural shift becomes even more apparent. Individuals should be able to maintain and present their own verified digital identity and history, rather than being at the mercy of siloed institutional databases. The Solid protocol makes this future technically possible.
This essay was written with Davi Ottenheimer, and originally appeared on The Inrupt Blog.
Massistant is the presumed successor to Chinese forensics tool, “MFSocket”, reported in 2019 and attributed to publicly traded cybersecurity company, Meiya Pico.
The forensics tool works in tandem with a corresponding desktop software.
Massistant gains access to device GPS location data, SMS messages, images, audio, contacts and phone services.
Meiya Pico maintains partnerships with domestic and international law enforcement partners, both as a surveillance hardware and software provider, as well as through training programs for law enforcement personnel.
The good news, per Balaam, is that Massistant leaves evidence of its compromise on the seized device, meaning users can potentially identify and delete the malware, either because the hacking tool appears as an app, or can be found and deleted using more sophisticated tools such as the Android Debug Bridge, a command line tool that lets a user connect to a device through their computer.
The bad news is that at the time of installing Massistant, the damage is done, and authorities already have the person’s data.
The developer of ICEBlock, an iOS app for anonymously reporting sightings of US Immigration and Customs Enforcement (ICE) officials, promises that it “ensures user privacy by storing no personal data.” But that claim has come under scrutiny. ICEBlock creator Joshua Aaron has been accused of making false promises regarding user anonymity and privacy, being “misguided” about the privacy offered by iOS, and of being an Apple fanboy. The issue isn’t what ICEBlock stores. It’s about what it could accidentally reveal through its tight integration with iOS.
Once you build a surveillance system, you can’t control who will use it:
A hacker working for the Sinaloa drug cartel was able to obtain an FBI official’s phone records and use Mexico City’s surveillance cameras to help track and kill the agency’s informants in 2018, according to a new US justice department report.
The incident was disclosed in a justice department inspector general’s audit of the FBI’s efforts to mitigate the effects of “ubiquitous technical surveillance,” a term used to describe the global proliferation of cameras and the thriving trade in vast stores of communications, travel, and location data.
[…]
The report said the hacker identified an FBI assistant legal attaché at the US embassy in Mexico City and was able to use the attaché’s phone number “to obtain calls made and received, as well as geolocation data.” The report said the hacker also “used Mexico City’s camera system to follow the [FBI official] through the city and identify people the [official] met with.”
Developing a new video conferencing application often begins with a peer-to-peer setup using WebRTC, facilitating direct data exchange between clients. While effective for small demonstrations, this method encounters scalability hurdles with increased participants. The data transmission load for each client escalates significantly in proportion to the number of users, as each client is required to send data to every other client except themselves (n-1).
In the scaling of video conferencing applications, Selective Forwarding Units (SFUs) are essential. Essentially a media stream routing hub, an SFU receives media and data flows from participants and intelligently determines which streams to forward. By strategically distributing media based on network conditions and participant needs, this mechanism minimizes bandwidth usage and greatly enhances scalability. Nearly every video conferencing application today uses SFUs.
In 2024, we announced Cloudflare Realtime (then called Cloudflare Calls), our suite of WebRTC products, and we also released Orange Meets, an open source video chat application built on top of our SFU.
We also realized that use of an SFU often comes with a privacy cost, as there is now a centralized hub that could see and listen to all the media contents, even though its sole job is to forward media bytes between clients as a data plane.
We believe end-to-end encryption should be the industry standard for secure communication and that’s why today we’re excited to share that we’ve implemented and open sourced end-to-end encryption in Orange Meets. Our generic implementation is client-only, so it can be used with any WebRTC infrastructure. Finally, our new designated committer distributed algorithm is verified in a bounded model checker to verify this algorithm handles edge cases gracefully.
End-to-end encryption for video conferencing is different than for text messaging
End-to-end encryption describes a secure communication channel whereby only the intended participants can read, see, or listen to the contents of the conversation, not anybody else. WhatsApp and iMessage, for example, are end-to-end-encrypted, which means that the companies that operate those apps or any other infrastructure can’t see the contents of your messages.
Whereas encrypted group chats are usually long-lived, highly asynchronous, and low bandwidth sessions, video and audio calls are short-lived, highly synchronous, and require high bandwidth. This difference comes with plenty of interesting tradeoffs, which influenced the design of our system.
We had to consider how factors like the ephemeral nature of calls, compared to the persistent nature of group text messages, also influenced the way we designed E2EE for Orange Meets. In chat messages, users must be able to decrypt messages sent to them while they were offline (e.g. while taking a flight). This is not a problem for real-time communication.
The bandwidth limitations around audio/video communication and the use of an SFU prevented us from using some of the E2EE technologies already available for text messages. Apple’s iMessage, for example, encrypts a message N-1 times for an N-user group chat. We can’t encrypt the video for each recipient, as that could saturate the upload capacity of Internet connections as well as slow down the client. Media has to be encrypted once and decrypted by each client while preserving secrecy around only the current participants of the call.
Messaging Layer Security (MLS)
Around the same time we were working on Orange Meets, we saw a lot of excitement around new apps being built with Messaging Layer Security (MLS), an IETF-standardized protocol that describes how you can do a group key exchange in order to establish end-to-end-encryption for group communication.
Previously, the only way to achieve these properties was to essentially run your own fork of the Signal protocol, which itself is more of a living protocol than a solidified standard. Since MLS is standardized, we’ve now seen multiple high-quality implementations appear, and we’re able to use them to achieve Signal-level security with far less effort.
Implementing MLS here wasn’t easy: it required a moderate amount of client modification, and the development and verification of an encrypted room-joining protocol. Nonetheless, we’re excited to be pioneering a standards-based approach that any customer can run on our network, and to share more details about how our implementation works.
We did not have to make any changes to the SFU to get end-to-end encryption working. Cloudflare’s SFU doesn’t care about the contents of the data forwarded on our data plane and whether it’s encrypted or not.
Orange Meets: the basics
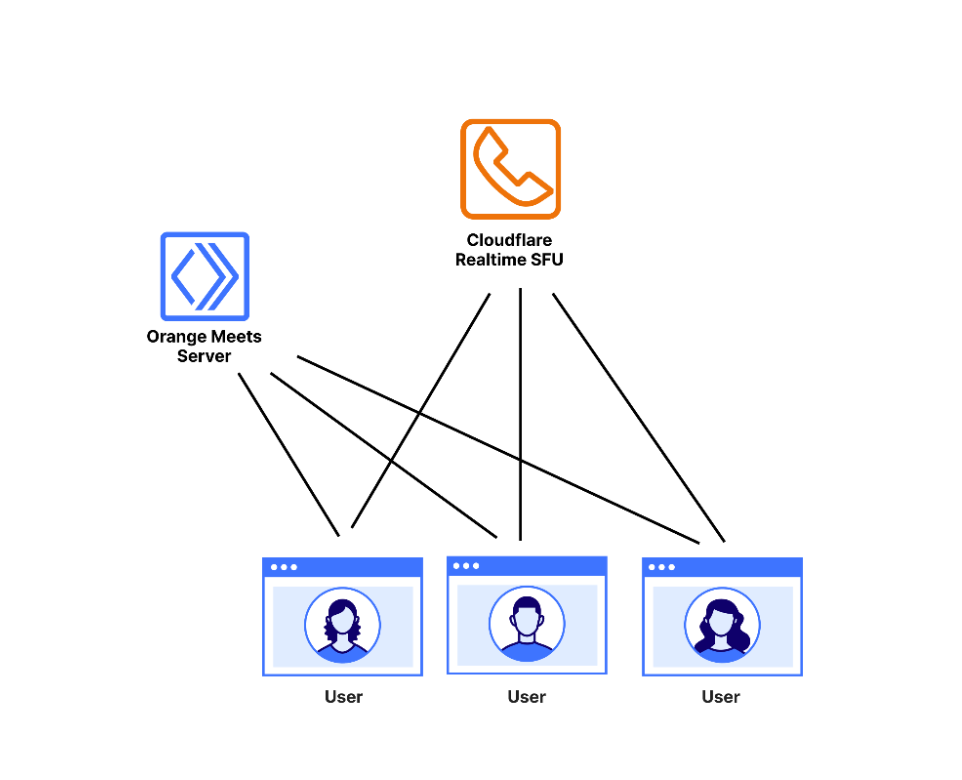
Orange Meets is a video calling application built on Cloudflare Workers that uses the Cloudflare Realtime SFU service as the data plane. The roles played by the three main entities in the application are as follows:
The user is a participant in the video call. They connect to the Orange Meets server and SFU, described below.
The Orange Meets Server is a simple service run on a Cloudflare Worker that runs the small-scale coordination logic of Orange Meets, which is concerned with which user is in which video call — called a room — and what the state of the room is. Whenever something in the room changes, like a participant joining or leaving, or someone muting themselves, the app server broadcasts the change to all room participants. You can use any backend server for this component, we just chose Cloudflare Workers for its convenience.
Cloudflare Realtime Selective Forwarding Unit (SFU) is a service that Cloudflare runs, which takes everyone’s audio and video and broadcasts it to everyone else. These connections are potentially lossy, using UDP for transmission. This is done because a dropped video frame from five seconds ago is not very important in the context of a video call, and so should not be re-sent, as it would be in a TCP connection.
The network topology of Orange Meets
Next, we have to define what we mean by end-to-end encryption in the context of video chat.
End-to-end encrypting Orange Meets
The most immediate way to end-to-end encrypt Orange Meets is to simply have the initial users agree on a symmetric encryption/decryption key at the beginning of a call, and just encrypt every video frame using that key. This is sufficient to hide calls from Cloudflare’s SFU. Some source-encrypted video conferencing implementations, such as Jitsi Meet, work this way.
The issue, however, is that kicking a malicious user from a call does not invalidate their key, since the keys are negotiated just once. A joining user learns the key that was used to encrypt video from before they joined. These failures are more formally referred to as failures of post-compromise security and perfect forward secrecy. When a protocol successfully implements these in a group setting, we call the protocol a continuous group key agreement protocol.
Fortunately for us, MLS is a continuous group key agreement protocol that works out of the box, and the nice folks at Phoenix R&D and Cryspen have a well-documented open-source Rust implementation of most of the MLS protocol.
All we needed to do was write an MLS client and compile it to WASM, so we could decrypt video streams in-browser. We’re using WASM since that’s one way of running Rust code in the browser. If you’re running a video conferencing application on a desktop or mobile native environment, there are other MLS implementations in your preferred programming language.
Our setup for encryption is as follows:
Make a web worker for encryption. We wrote a web worker in Rust that accepts a WebRTC video stream, broken into individual frames, and encrypts each frame. This code is quite simple, as it’s just an MLS encryption:
Postprocess outgoing audio/video. We take our normal stream and, using some newer features of the WebRTC API, add a transform step to it. This transform step simply sends the stream to the worker:
Once we do this for both audio and video streams, we’re done.
Handling different codec behaviors
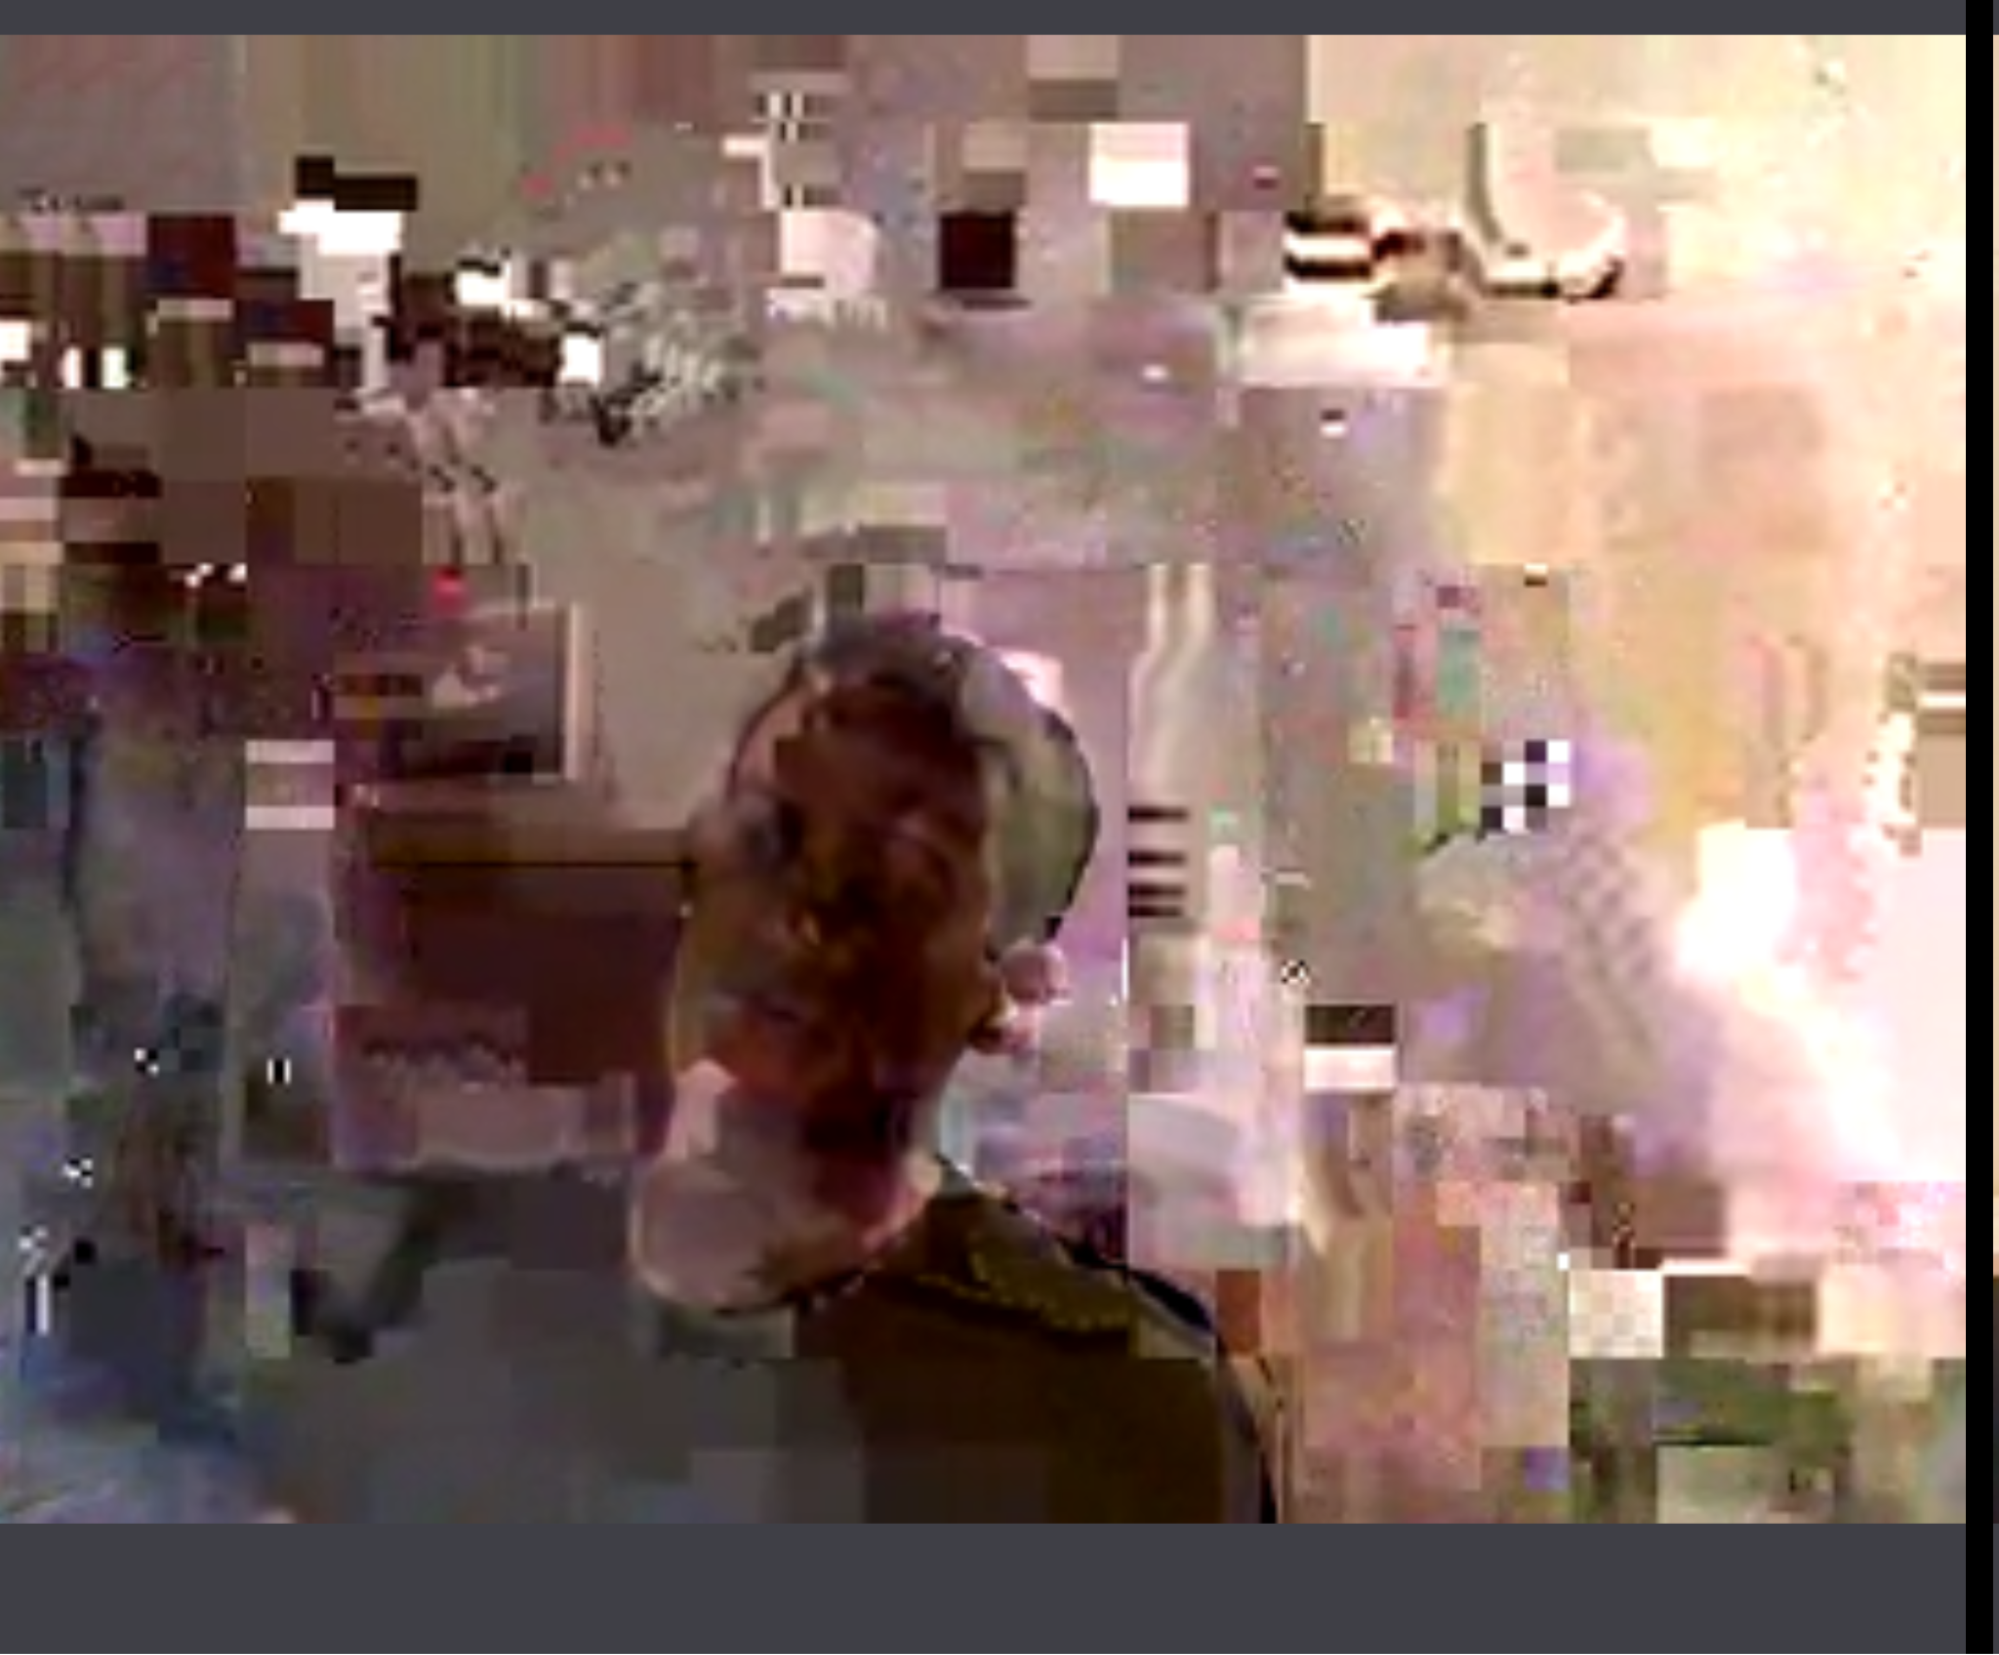
The streams are now encrypted before sending and decrypted before rendering, but the browser doesn’t know this. To the browser, the stream is still an ordinary video or audio stream. This can cause errors to occur in the browser’s depacketizing logic, which expects to see certain bytes in certain places, depending on the codec. This results in some extremely cypherpunk artifacts every dozen seconds or so:
Fortunately, this exact issue was discovered by engineers at Discord, who handily documented it in their DAVE E2EE videocalling protocol. For the VP8 codec, which we use by default, the solution is simple: split off the first 1–10 bytes of each packet, and send them unencrypted:
fn split_vp8_header(frame: &[u8]) -> Option<(&[u8], &[u8])> {
    // If this is a keyframe, keep 10 bytes unencrypted. Otherwise, 1 is enough
    let is_keyframe = frame[0] >> 7 == 0;
    let unencrypted_prefix_size = if is_keyframe { 10 } else { 1 };
    frame.split_at_checked(unencrypted_prefix_size)
}
These bytes are not particularly important to encrypt, since they only contain versioning info, whether or not this frame is a keyframe, some constants, and the width and height of the video.
And that’s truly it for the stream encryption part! The only thing remaining is to figure out how we will let new users join a room.
“Join my Orange Meet”
Usually, the only way to join the call is to click a link. And since the protocol is encrypted, a joining user needs to have some cryptographic information in order to decrypt any messages. How do they receive this information, though? There are a few options.
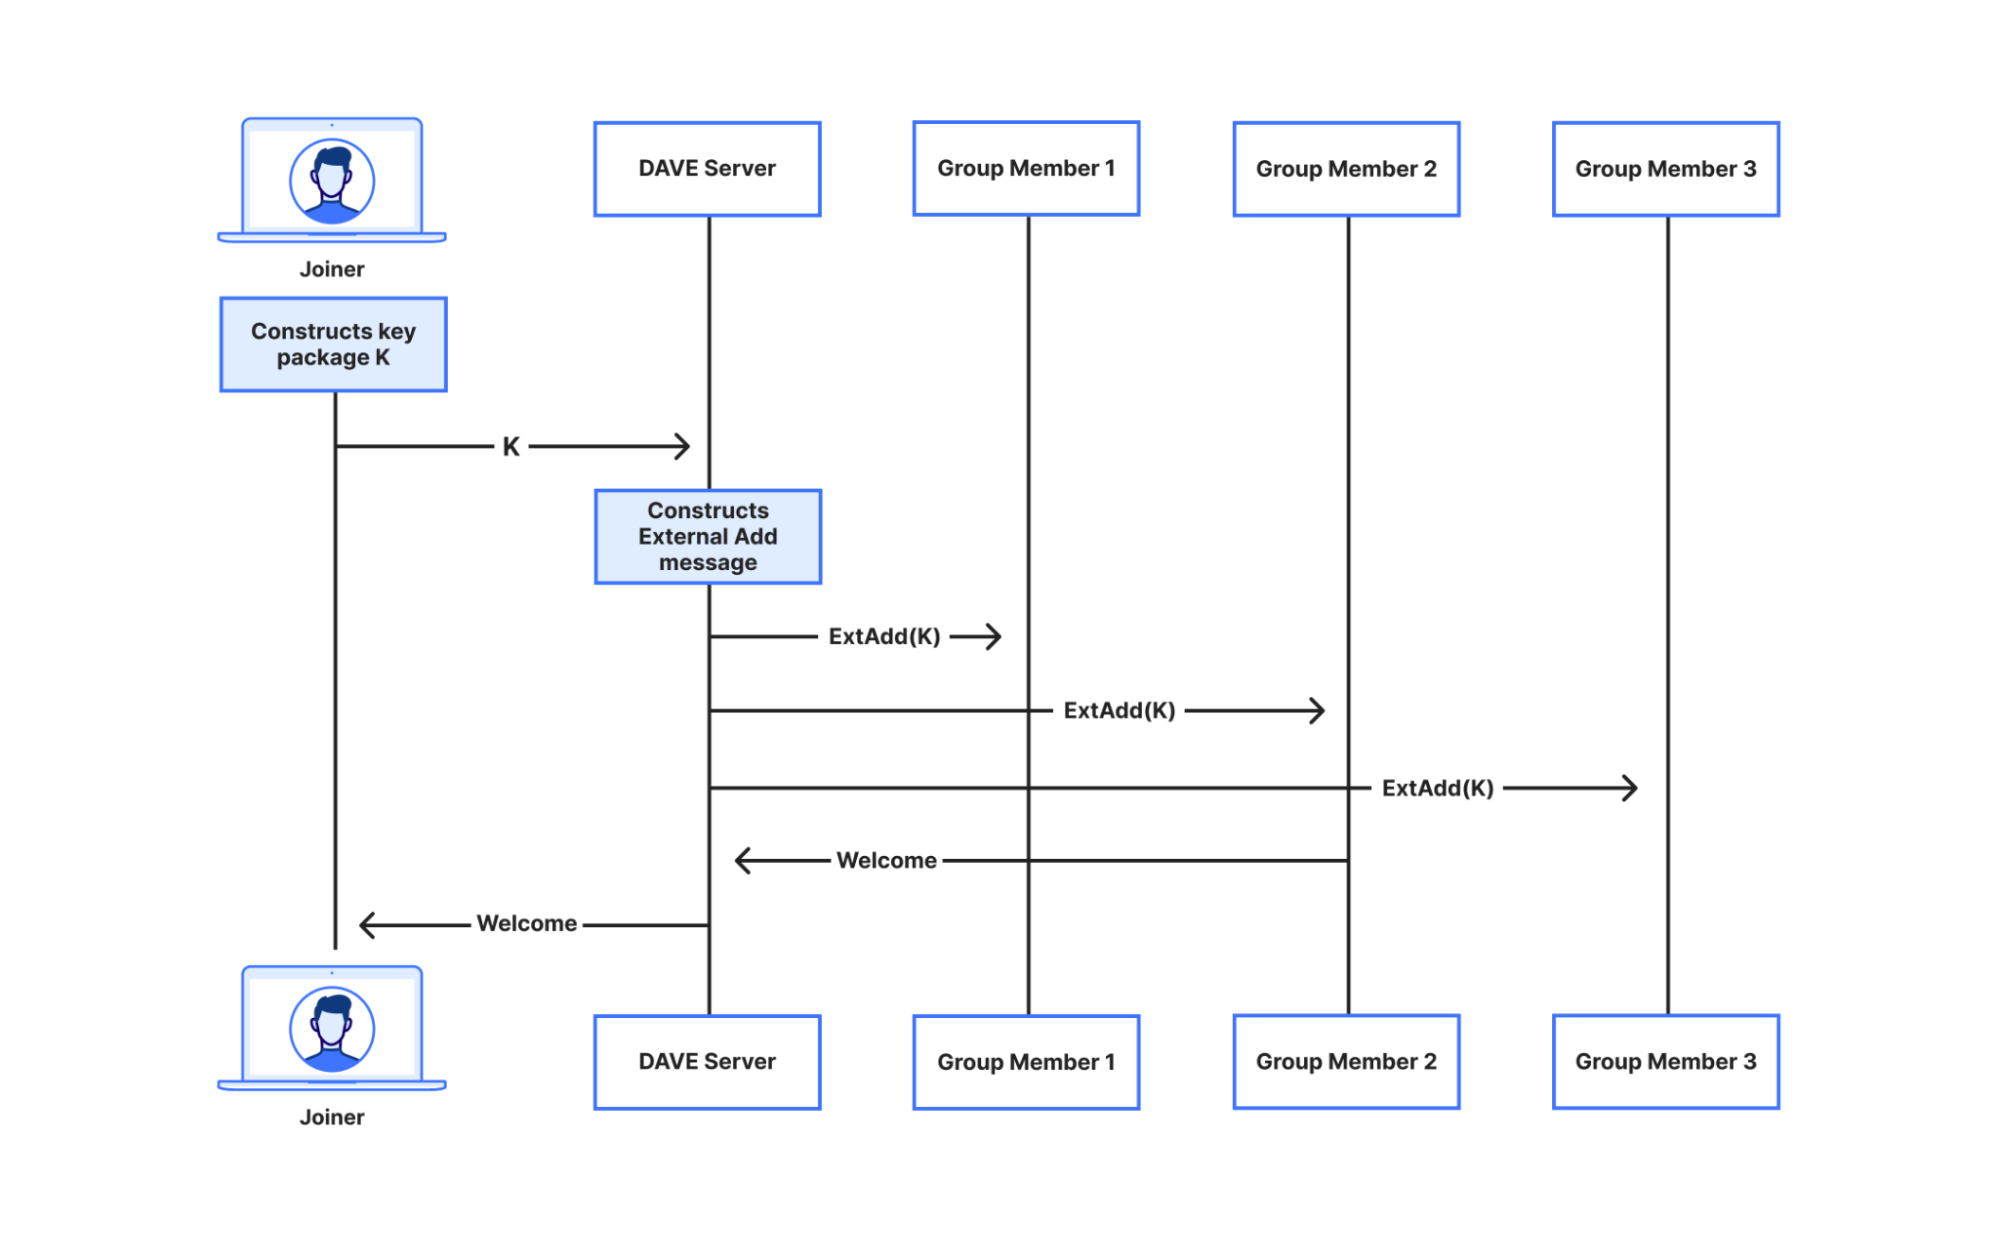
DAVE does it by using an MLS feature called external proposals. In short, the Discord server registers itself as an external sender, i.e., a party that can send administrative messages to the group, but cannot receive any. When a user wants to join a room, they provide their own cryptographic material, called a key package, and the server constructs and sends an MLS External Add message to the group to let them know about the new user joining. Eventually, a group member will commit this External Add, sending the joiner a Welcome message containing all information necessary to send and receive video.
A user joining a group via MLS external proposals. Recall the Orange Meets app server functions as a broadcast channel for the whole group. We consider a group of 3 members. We write member #2 as the one committing to the proposal, but this can be done by any member. Member #2 also sends a Commit message to the other members, but we omit this for space.
This is a perfectly viable way to implement room joining, but implementing it would require us to extend the Orange Meets server logic to have some concept of MLS. Since part of our goal is to keep things as simple as possible, we would like to do all our cryptography client-side.
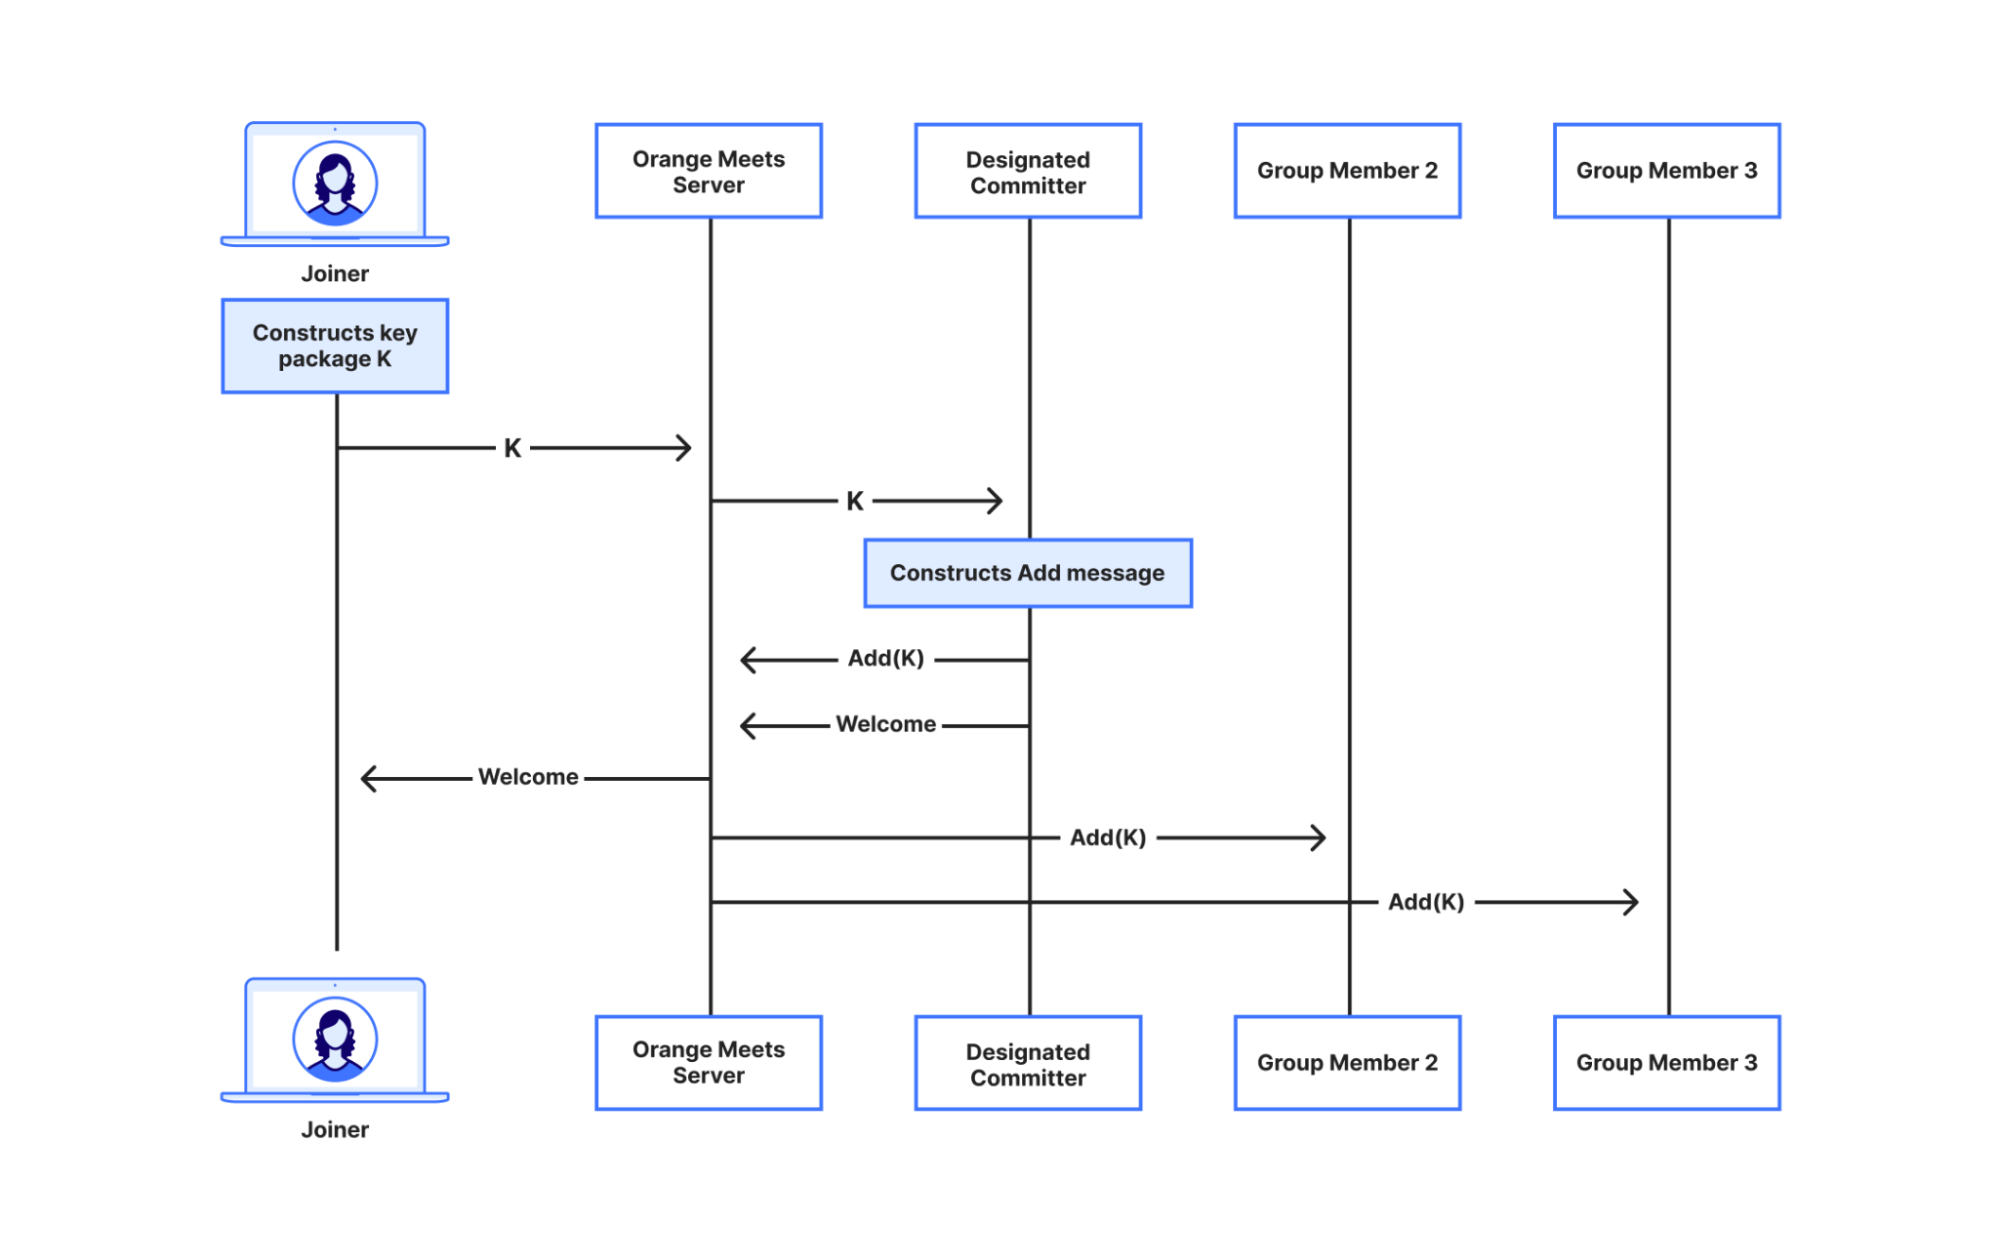
So instead we do what we call the designated committer algorithm. When a user joins a group, they send their cryptographic material to one group member, the designated committer, who then constructs and sends the Add message to the rest of the group. Similarly, when notified of a user’s exit, the designated committer constructs and sends a Remove message to the rest of the group. With this setup, the server’s job remains nothing more than broadcasting messages! It’s quite simple too—the full implementation of the designated committer state machine comes out to 300 lines of Rust, including the MLS boilerplate, and it’s about as efficient.
A user joining a group via the designated committer algorithm.
One cool property of the designated committer algorithm is that something like this isn’t possible in a text group chat setting, since any given user (in particular, the designated committer) may be offline for an arbitrary period of time. Our method works because it leverages the fact that video calls are an inherently synchronous medium.
Verifying the Designated Committer Algorithm with TLA+
The designated committer algorithm is a pretty neat simplification, but it comes with some non-trivial edge cases that we need to make sure we handle, such as:
How do we make sure there is only one designated committer at a time? The designated committer is the alive user with the smallest index in the MLS group state, which all users share.
What happens if the designated committer exits? Then the next user will take its place. Every user keeps track of pending Adds and Removes, so it can continue where the previous designated committer left off.
If a user has not caught up to all messages, could they think they’re the designated committer? No, they have to believe first that all prior eligible designated committers are disconnected.
To make extra sure that this algorithm was correct, we formally modeled it and put it through the TLA+ model checker. To our surprise, it caught some low-level bugs! In particular, it found that, if the designated committer dies while adding a user, the protocol does not recover. We fixed these by breaking up MLS operations and enforcing a strict ordering on messages locally (e.g., a Welcome is always sent before its corresponding Add).
You can find an explainer, lessons learned, and the full PlusCal program (a high-level language that compiles to TLA+) here. The caveat, as with any use of a bounded model checker, is that the checking is, well, bounded. We verified that no invalid protocol states are possible in a group of up to five users. We think this is good evidence that the protocol is correct for an arbitrary number of users. Because there are only two distinct roles in the protocol (designated committer and other group member), any weird behavior ought to be reproducible with two or three users, max.
Preventing Man-in-the-Middle attacks
One important concern to address in any end-to-end encryption setup is how to prevent the service provider from replacing users’ key packages with their own. If the Orange Meets app server did this, and colluded with a malicious SFU to decrypt and re-encrypt video frames on the fly, then the SFU could see all the video sent through the network, and nobody would know.
To resolve this, like DAVE, we include a safety number in the corner of the screen for all calls. This number uniquely represents the cryptographic state of the group. If you check out-of-band (e.g., in a Signal group chat) that everyone agrees on the safety number, then you can be sure nobody’s key material has been secretly replaced.
In fact, you could also read the safety number aloud in the video call itself, but doing this is not provably secure. Reading a safety number aloud is an in-band verification mechanism, i.e., one where a party authenticates a channel within that channel. If a malicious app server colluding with a malicious SFU were able to construct believable video and audio of the user reading the safety number aloud, it could bypass this safety mechanism. So if your threat model includes adversaries that are able to break into a Worker and Cloudflare’s SFU, and simultaneously generate real-time deep-fakes, you should use out-of-band verification 😄.
Future work
There are some areas we could improve on:
There is another attack vector for a malicious app server: it is possible to simply serve users malicious Javascript. This problem, more generally called the Javascript Cryptography Problem, affects any in-browser application where the client wants to hide data from the server. Fortunately, we are working on a standard to address this, called Web Application Manifest Consistency, Integrity, and Transparency. In short, like our Code Verify solution for WhatsApp, this would allow every website to commit to the Javascript it serves, and have a third party create an auditable log of the code. With transparency, malicious Javascript can still be distributed, but at least now there is a log that records the code.
We can make out-of-band authentication easier by placing trust in an identity provider. Using OpenPubkey, it would be possible for a user to get the identity provider to sign their cryptographic material, and then present that. Then all the users would check the signature before using the material. Transparency would also help here to ensure no signatures were made in secret.
Conclusion
We built end-to-end encryption into the Orange Meets video chat app without a lot of engineering time, and by modifying just the client code. To do so, we built a WASM (compiled from Rust) service worker that sets up an MLS group and does stream encryption and decryption, and designed a new joining protocol for groups, called the designated committer algorithm, and formally modeled it in TLA+. We made comments for all kinds of optimizations that are left to do, so please send us a PR if you’re so inclined!
Good article from 404 Media on the cozy surveillance relationship between local Oregon police and ICE:
In the email thread, crime analysts from several local police departments and the FBI introduced themselves to each other and made lists of surveillance tools and tactics they have access to and felt comfortable using, and in some cases offered to perform surveillance for their colleagues in other departments. The thread also includes a member of ICE’s Homeland Security Investigations (HSI) and members of Oregon’s State Police. In the thread, called the “Southern Oregon Analyst Group,” some members talked about making fake social media profiles to surveil people, and others discussed being excited to learn and try new surveillance techniques. The emails show both the wide array of surveillance tools that are available to even small police departments in the United States and also shows informal collaboration between local police departments and federal agencies, when ordinarily agencies like ICE are expected to follow their own legal processes for carrying out the surveillance.
Two articles crossed my path recently. First, a discussion of all the video Waymo has from outside its cars: in this case related to the LA protests. Second, a discussion of all the video Tesla has from inside its cars.
Lots of things are collecting lots of video of lots of other things. How and under what rules that video is used and reused will be a continuing source of debate.
Paragon is an Israeli spyware company, increasingly in the news (now that NSO Group seems to be waning). “Graphite” is the name of its product. Citizen Lab caught it spying on multiple European journalists with a zero-click iOS exploit:
On April 29, 2025, a select group of iOS users were notified by Apple that they were targeted with advanced spyware. Among the group were two journalists that consented for the technical analysis of their cases. The key findings from our forensic analysis of their devices are summarized below:
Our analysis finds forensic evidence confirming with high confidence that both a prominent European journalist (who requests anonymity), and Italian journalist Ciro Pellegrino, were targeted with Paragon’s Graphite mercenary spyware.
We identify an indicator linking both cases to the same Paragon operator.
Apple confirms to us that the zero-click attack deployed in these cases was mitigated as of iOS 18.3.1 and has assigned the vulnerability CVE-2025-43200.
Our analysis is ongoing.
The list of confirmed Italian cases is in the report’s appendix. Italy has recently admitted to using the spyware.
A data broker owned by the country’s major airlines, including Delta, American Airlines, and United, collected U.S. travellers’ domestic flight records, sold access to them to Customs and Border Protection (CBP), and then as part of the contract told CBP to not reveal where the data came from, according to internal CBP documents obtained by 404 Media. The data includes passenger names, their full flight itineraries, and financial details.
The only links are from The Daily Mail and The Mirror, but a marital affair was discovered because the cheater was recorded using his smart toothbrush at home when he was supposed to be at work.
Sooner or later, it’s going to happen. AI systems will start acting as agents, doing things on our behalf with some degree of autonomy. I think it’s worth thinking about the security of that now, while its still a nascent idea.
In 2019, I joined Inrupt, a company that is commercializing Tim Berners-Lee’s open protocol for distributed data ownership. We are working on a digital wallet that can make use of AI in this way. (We used to call it an “active wallet.” Now we’re calling it an “agentic wallet.”)
I talked aboutthis a bit at the RSA Conference earlier this week, in my keynote talk about AI and trust. Any useful AI assistant is going to require a level of access—and therefore trust—that rivals what we currently our email provider, social network, or smartphone.
This Active Wallet is an example of an AI assistant. It’ll combine personal information about you, transactional data that you are a party to, and general information about the world. And use that to answer questions, make predictions, and ultimately act on your behalf. We have demos of this running right now. At least in its early stages. Making it work is going require an extraordinary amount of trust in the system. This requires integrity. Which is why we’re building protections in from the beginning.
Visa is also thinking about this. It justannounced a protocol that uses AI to help people make purchasing decisions.
I like Visa’s approach because it’s an AI-agnostic standard. I worry a lot about lock-in and monopolization of this space, so anything that lets people easily switch between AI models is good. And I like that Visa is working with Inrupt so that the data is decentralized as well. Here’s our announcement about its announcement:
This isn’t a new relationship—we’ve been working together for over two years. We’ve conducted a successful POC and now we’re standing up a sandbox inside Visa so merchants, financial institutions and LLM providers can test our Agentic Wallets alongside the rest of Visa’s suite of Intelligent Commerce APIs.
For that matter, we welcome any other company that wants to engage in the world of personal, consented Agentic Commerce to come work with us as well.
I joined Inrupt years ago because I thought that Solid could do for personal data what HTML did for published information. I liked that the protocol was an open standard, and that it distributed data instead of centralizing it. AI agents need decentralized data. “Wallet” is a good metaphor for personal data stores. I’m hoping this is another step towards adoption.
The company doesn’t keep logs, so couldn’t turn over data:
Windscribe, a globally used privacy-first VPN service, announced today that its founder, Yegor Sak, has been fully acquitted by a court in Athens, Greece, following a two-year legal battle in which Sak was personally charged in connection with an alleged internet offence by an unknown user of the service.
The case centred around a Windscribe-owned server in Finland that was allegedly used to breach a system in Greece. Greek authorities, in cooperation with INTERPOL, traced the IP address to Windscribe’s infrastructure and, unlike standard international procedures, proceeded to initiate criminal proceedings against Sak himself, rather than pursuing information through standard corporate channels.
It is poor civic hygiene to install technologies that could someday facilitate a police state.
It’s something a bunch of us were saying at the time, in reference to the vast NSA’s surveillance capabilities.
I have been thinking of that quote a lot as I read newsstoriesof President Trump firing the Director of the National Security Agency. General Timothy Haugh.
We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.
The NSA alreadyspiesonAmericans in a variety of ways. But that’s always been a sideline to its main mission: spying on the rest of the world. Once Trump replaces Haugh with a loyalist, the NSA’s vast surveillance apparatus can be refocused domestically.
Giving that agency all those powers in the 1990s, in the 2000s after the terrorist attacks of 9/11, and in the 2010s was always a mistake. I fear that we are about to learn how big a mistake it was.
Here’s PGP creator Phil Zimmerman in 1996, spelling it out even more clearly:
The Clinton Administration seems to be attempting to deploy and entrench a communications infrastructure that would deny the citizenry the ability to protect its privacy. This is unsettling because in a democracy, it is possible for bad people to occasionally get elected—sometimes very bad people. Normally, a well-functioning democracy has ways to remove these people from power. But the wrong technology infrastructure could allow such a future government to watch every move anyone makes to oppose it. It could very well be the last government we ever elect.
When making public policy decisions about new technologies for the government, I think one should ask oneself which technologies would best strengthen the hand of a police state. Then, do not allow the government to deploy those technologies. This is simply a matter of good civic hygiene.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.