Organizations building event-driven applications on Amazon EventBridge typically start with a single custom event bus in one account. This works well when a single team owns the architecture. As adoption grows across the organization, though, things get complicated. AWS best practices recommend a multi-account structure, which means each team runs in its own account. To route events between them, teams create multiple event buses connected through cross-account rules or bus-to-bus configurations. This workaround reintroduces the operational complexity that serverless architectures are meant to eliminate. Platform teams lose visibility into who is subscribing to which events, cross-account and bus-to-bus routing charges compound quickly, and teams that need capabilities like event ordering are forced to build complex workarounds or adopt entirely different technologies.
Today, we are announcing an enhanced custom event bus in Amazon EventBridge, purpose-built for organizations scaling event-driven applications across teams and accounts. With the new enhanced custom event bus, you can deploy a single, centralized event bus shared across all AWS accounts in your organization, with ordering guarantees, a simplified Subscriber resource, and a new pricing model that delivers improved economics at scale and cost allocation for publishers and subscribers.
Let’s try it out
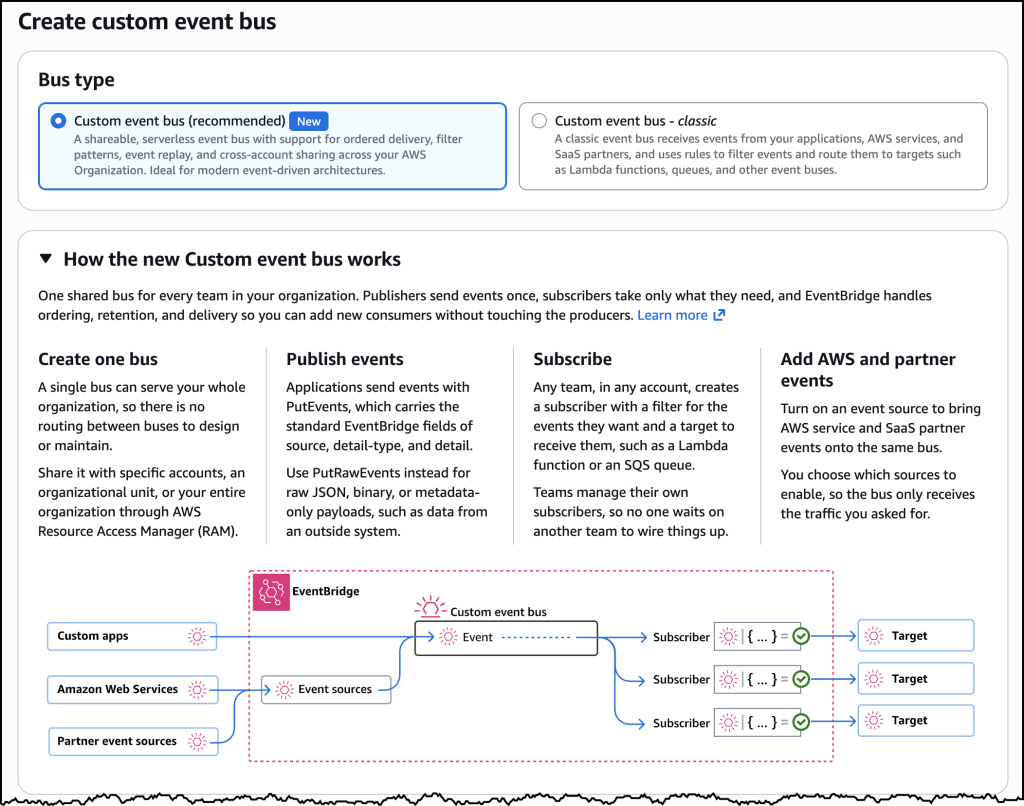
To get started with an enhanced custom event bus, I navigated to the EventBridge console in the AWS Management Console and opened the Create custom event bus page. I selected Custom event bus, the recommended option labeled New. The page also offered Custom event bus – classic, which continues to receive events and route them with rules and targets. Below the selection, EventBridge showed how the new bus works. One shared bus serves every team in the organization. Publishers send events, subscribers consume only what they need, and EventBridge handles ordering, retention, routing, and delivery.
The Create custom event bus page. Custom event bus is the recommended new option, with ordered delivery, filter patterns, event replay, and sharing across your AWS organization. Custom event bus – classic remains available for existing workloads.
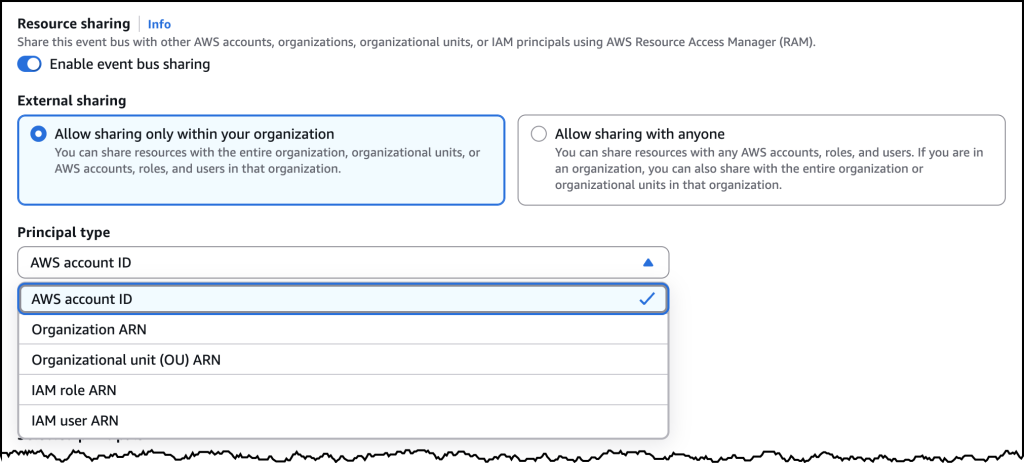
Next, I configured resource sharing. I turned on Enable event bus sharing and selected Allow sharing only within your organization. I chose AWS account ID as the principal type. I could also share with an organization, an organizational unit, or an AWS Identity and Access Management (IAM) role or user. Sharing uses AWS Resource Access Manager (AWS RAM), so I did not have to set up cross-account permissions or bus-to-bus routing myself.
Resource sharing on the new custom event bus. I enabled sharing within my organization through AWS RAM and selected an AWS account as the principal, which is how teams publish and subscribe on the same bus without extra routing.
Organization-wide sharing
With the new enhanced custom event bus, you can create a single event bus and share it across all AWS accounts in your organization. Platform teams deploy one bus and establish it as the central event backbone, eliminating the need to configure cross-account permissions or bus-to-bus routing. Application teams across your organization can publish and subscribe to events on the same bus without waiting for infrastructure provisioning.
Publishers send events without needing to know which teams consume them, and subscribers create their own Subscriptions independently. Platform teams maintain visibility into all event flows and fine-grained control over who can publish and consume events. The new enhanced custom event bus has a default quota of 10,000 Subscribers per bus, and you can request a higher quota. That reduces the fragmentation that occurs when subscriber limits force you to split across multiple buses.
Event ordering
Event-driven architectures work best when consumers are designed around asynchronous patterns, where the order of events does not matter. There are a few cases where order does matter. In a logistics application, driver location updates must arrive in sequence. Out-of-sequence events cause routing algorithms to make decisions based on stale data.
The enhanced custom event bus supports both patterns on the same bus. Publishers can include an EventGroupId when sending events. EventBridge delivers events that share the same EventGroupId in sequence to Subscribers that chose ordered delivery. Other subscribers on that bus can receive the same events without ordering. You can keep events for each driver in the correct order without building complex workarounds, while the rest of your consumers stay fully asynchronous.
To support ordered processing, the enhanced custom event bus includes synchronous invocation for targets like AWS Lambda. Synchronous mode confirms successful processing before acknowledging the event, eliminating the common pattern of placing Amazon Simple Queue Service (Amazon SQS) between an event bus and Lambda to ensure reliability.
Subscriptions
The enhanced custom event bus introduces the Subscriber resource, which combines event filtering, target configuration, retry policies, and dead-letter destinations into a single, manageable unit. Today, achieving the same outcome with EventBridge requires configuring separate rules, targets, and retry settings across multiple resources. Subscribers simplify this by giving each consumer one resource that defines what events they want, where to deliver them, and how to handle failures.
Subscribers also include variable start time options, making it easier for teams to onboard new consumers or replay events to recover from application errors or hydrate new applications.
Event evaluation
Publishers can turn on content-based deduplication so EventBridge detects and drops retries of the same event from the payload itself. You do not have to generate and track a deduplication ID when a timeout or a partial failure sends the same event twice. EventBridge hashes the meaningful parts of the event and collapses matches that arrive within five minutes, which gives those retries exactly-once delivery semantics instead of EventBridge’s usual at-least-once model. If you already stamp your own idempotency token, keep using it. Content-based deduplication is for sources that cannot reliably identify the same event on a retry.
Subscribers can use JSONata expressions to reshape an event before it reaches a target, extracting fields, renaming them, or computing new values when a downstream API expects a different shape. If you already produce Apache Avro or Protocol Buffers events, EventBridge can deserialize those payloads to JSON, allowing subscribers fine grained filtering and routing on the full event payload without having to consume, deserialize, and match or discard on their own.
New pricing model
The enhanced custom event bus uses a new ingress and egress throughput pricing model. Publishers pay for events ingested, and subscribers pay for events delivered. This replaces the per-event model where cross-account and bus-to-bus routing charges compound in multi-bus architectures. For pricing details, visit the EventBridge pricing page.
Existing EventBridge custom event buses continue to work as they do today with no changes required. They now appear as Custom event bus – classic. The enhanced custom event bus is a new resource that you adopt at your own pace. In the console, it appears as Custom event bus.
Now available
The enhanced custom event bus is available today in the US East (N. Virginia, Ohio), US West (Oregon), Europe (Ireland, Frankfurt, Stockholm, Spain), and Asia Pacific (Hong Kong, Malaysia, Mumbai, Singapore, Sydney, Thailand, Tokyo) Regions. You can create your first enhanced custom event bus through the AWS Management Console, AWS Command Line Interface (AWS CLI), or EventBridge APIs. To get started, visit the EventBridge documentation or try it out directly in the EventBridge console.
The F-Droid project has announced
the release of F-Droid 2.0, which is a complete redesign of the official
app. Notable changes in the release include making it easier to discover and
install applications, more useful app categories, improved search, and
much more.
For more than a decade, F-Droid has helped people discover and install free
and open source Android apps. F-Droid 2.0 builds on that foundation with a
modern interface, better app discovery, improved search, and a simpler
experience that works well, whether you’re new to F-Droid or have been using it
for years.
This isn’t just a visual refresh. The user experience was redesigned to
integrate smoothly with current Android patterns, like Material Design, while
keeping familiar F-Droid interactions in place. Key components were reworked and
rewritten using Kotlin Compose, the standard toolkit these days, creating a
foundation that will help us deliver improvements more quickly in the years
ahead.
Sudheendra Raghav Neela, a member of a group of researchers from Graz University of Technology, has announced the
release of research into file-notification attacks that would allow spying on
user activity on Android, Linux, macOS, and Windows. The group has published a paper with
details on the research as well as a web site
with demonstrations of the vulnerabilities.
On Linux, an attacker can use inotifywatch to
monitor a directory to conduct an inter-keystroke timing attack—even if
they do not have read access to the files within a directory. The group also
discovered a method to conduct a UI-redress
attack (or “clickjacking” attack) on
KDE 5 and KDE 6 by monitoring /usr/bin/pkexec to detect when Polkit spawns an authentication
prompt. An attacker could draw a fake password window on top of the real window
to collect a user’s credentials.
Both of these flaws are still present today,
though the Linux kernel did partially mitigate the issue with a
fix that was included in the 5.10.248, 5.15.198, 6.1.160, 6.6.120, 6.12.65,
and 6.18.3 kernels shipped in January. See the web site for more information and
a mitigation to prevent password-prompt windows from losing focus.
This post is co-written with Kirill Tishenkov, Alexandru Pisarenco, Upendra Kambhampati, and Sabariesh Ganesan from Delivery Hero.
Real-time ad measurement is one of the harder streaming problems in advertising. Every impression and click has to be accurate enough to bill a vendor for, and fresh enough for the ad server to act on. In this post, we describe how Delivery Hero moved its ad measurement pipeline from hourly batch processing to real time on Amazon Managed Service for Apache Flink. Delivery Hero, based in Berlin, Germany, is one of the world’s leading local delivery platforms, operating across Asia, Europe, Latin America, the Middle East, and North Africa. Working with more than 1.5 million restaurant partners and local vendors in around 65 countries, Delivery Hero handles millions of orders for food, groceries, and everyday essentials daily.
At the center of Delivery Hero’s business sits an advertising platform that connects vendors and brands with millions of active consumers. The platform handles tens of thousands of messages per second and processes billions of ad events per day, supporting an advertising revenue stream that reached almost EUR 1.5 billion in 2025. Every impression served and every click recorded must satisfy two requirements at once. The data must be accurate enough to bill vendors fairly, and fresh enough for the ad server to act on in real time. Delivery Hero replaced its batch-oriented measurement system with a fully real-time pipeline built on Amazon Managed Service for Apache Flink. The new pipeline cut infrastructure costs by more than half and reached a level of data quality the previous system could not.
Challenges with the legacy system
The legacy ads measurement system consumed impression, click, and order events from message queues. It enriched them through synchronous API calls for campaign metadata and product lookups, then wrote hourly aggregated metrics to a reporting database. This design worked at a modest scale, but five structural problems emerged as traffic grew.
No event-time semantics, and slow processing. The pipeline bucketed events by the time it processed them rather than the time they occurred, because most events arrived without a usable event timestamp. Results were internally consistent, but they skewed whenever ingestion lagged or events arrived out of order. That widened the error bar on every time-sensitive metric, including return on ad spend (ROAS). The bigger cost was speed. Metrics were assembled in hourly batches, so the average gap between when an event occurred and when it was recorded was 61 minutes. The platform was reacting to clicks and impressions up to an hour after the fact, far too late for budget pacing or ad serving.
Synchronous enrichment capped how far the system could scale. Enrichment is the step that attaches business context to a raw ad event: which campaign it belongs to, which vendor owns it, and which product was advertised. In the legacy system, every event triggered a chain of blocking external API calls to fetch that context. During traffic spikes, such as a flash sale or a back-to-school surge, exhausted connection pools cascaded into billing, ad serving, and reporting simultaneously. There was no back-pressure mechanism and no way to scale enrichment independently of event ingestion.
The database behind the pipeline was built for a very different access pattern. The pipeline kept its working data in a NoSQL document database: deduplication keys, attribution history, and running totals. The platform inherited that database from its pre-streaming era, when ad measurement looked like document storage and retrieval. The workload then evolved into continuous deduplication, multi-day attribution lookups, and rolling aggregation. Every event ended up triggering a full document read and write against a database designed for occasional access, not per-event mutation. Read/write amplification stored far more data than the logic needed, every write triggered index updates and collection scans, and storage costs grew in lockstep with query latency. At peak load, this often tipped into production outages.
Reprocessing was a project, not a capability. Recovery from a bug, a traffic spike, or a corrupted upstream batch required different tooling for every consuming system. Billing replay was a hand-rolled combination of Google Cloud BigQuery tables, Pub/Sub topics, and custom CLI scripts. Reporting replay ran as a separate daily Airflow job with a one-hour-per-day cost and a six-month horizon. Campaigns and credits events had no replay path at all. Every recovery was a coordination exercise across teams. Every event type that could not be replayed was a class of problems that could only be patched manually after the fact.
Incomplete event context corrupted downstream data quality. Enrichment was synchronous and best-effort, so the pipeline still wrote through events that failed a lookup or arrived malformed, leaving their fields blank. The pipeline had no mechanism to recover the missing context later. Three gaps mattered most:
Missing session rate: the share of events that landed without a usable session ID, leaving the interaction unattached to the user browsing session it belonged to. At 30–40 percent, roughly a third of all events could not be tied back to a session, breaking any session-scoped analysis or feature.
Missing customer identifiers (IDs): the share of events with no customer ID, severing the link between an ad interaction and the customer who generated it and weakening attribution and personalization.
Missing impression timestamps: the share of impression events lacking a reliable event-time timestamp (the same root cause as the processing-time fallback described earlier). At 91 percent, most impressions had no trustworthy event time, forcing the processing-time approximation and widening the error bar on every time-based metric.
These omissions propagated silently into the reporting metrics and into the session-scoped features consumed by machine learning (ML) models for campaign ranking, conversion-rate estimation, and anomaly detection.
Why Amazon Managed Service for Apache Flink
The team set three non-negotiable requirements. First, fault-tolerant data processing, to eliminate data loss. Second, stateful stream processing that could hold multiple days of interaction history in low-cost, low-latency storage. Third, fully managed infrastructure, so engineers could focus on application logic rather than cluster operations.
The team selected Apache Flink because it satisfies all three requirements natively, without bolting on external systems. Its event-time watermark model helps place out-of-order events in the correct time window even when they arrive late. Its RocksDB state backend holds large keyed state on disk without Java Virtual Machine (JVM) heap pressure.
The team chose Amazon Managed Service for Apache Flink over self-hosted Flink on Amazon Elastic Kubernetes Service (Amazon EKS) to eliminate the operational burden of managing JobManagers, TaskManagers, and checkpoint storage. Amazon Kinesis Data Streams serves as the upstream event bus, with two streams: one for user event actions (impressions and clicks) and one for orders. The team chose Kinesis Data Streams over Amazon Managed Streaming for Apache Kafka (Amazon MSK) for cost efficiency at this topology.
Amazon DynamoDB holds campaign and product reference data, queried through Flink’s Async I/O API to enrich events without blocking the processing pipeline. AWS Secrets Manager stores ad event decryption keys, retrieved once at job startup. Amazon Simple Storage Service (Amazon S3) stores granular event logs in Avro format and serves as the incremental checkpoint store for Flink state. Amazon EventBridge Pipes bridged Amazon Simple Queue Service (Amazon SQS) to Kinesis in the minimum viable product (MVP) phase without any custom code, cutting time-to-production by two weeks.
Solution architecture
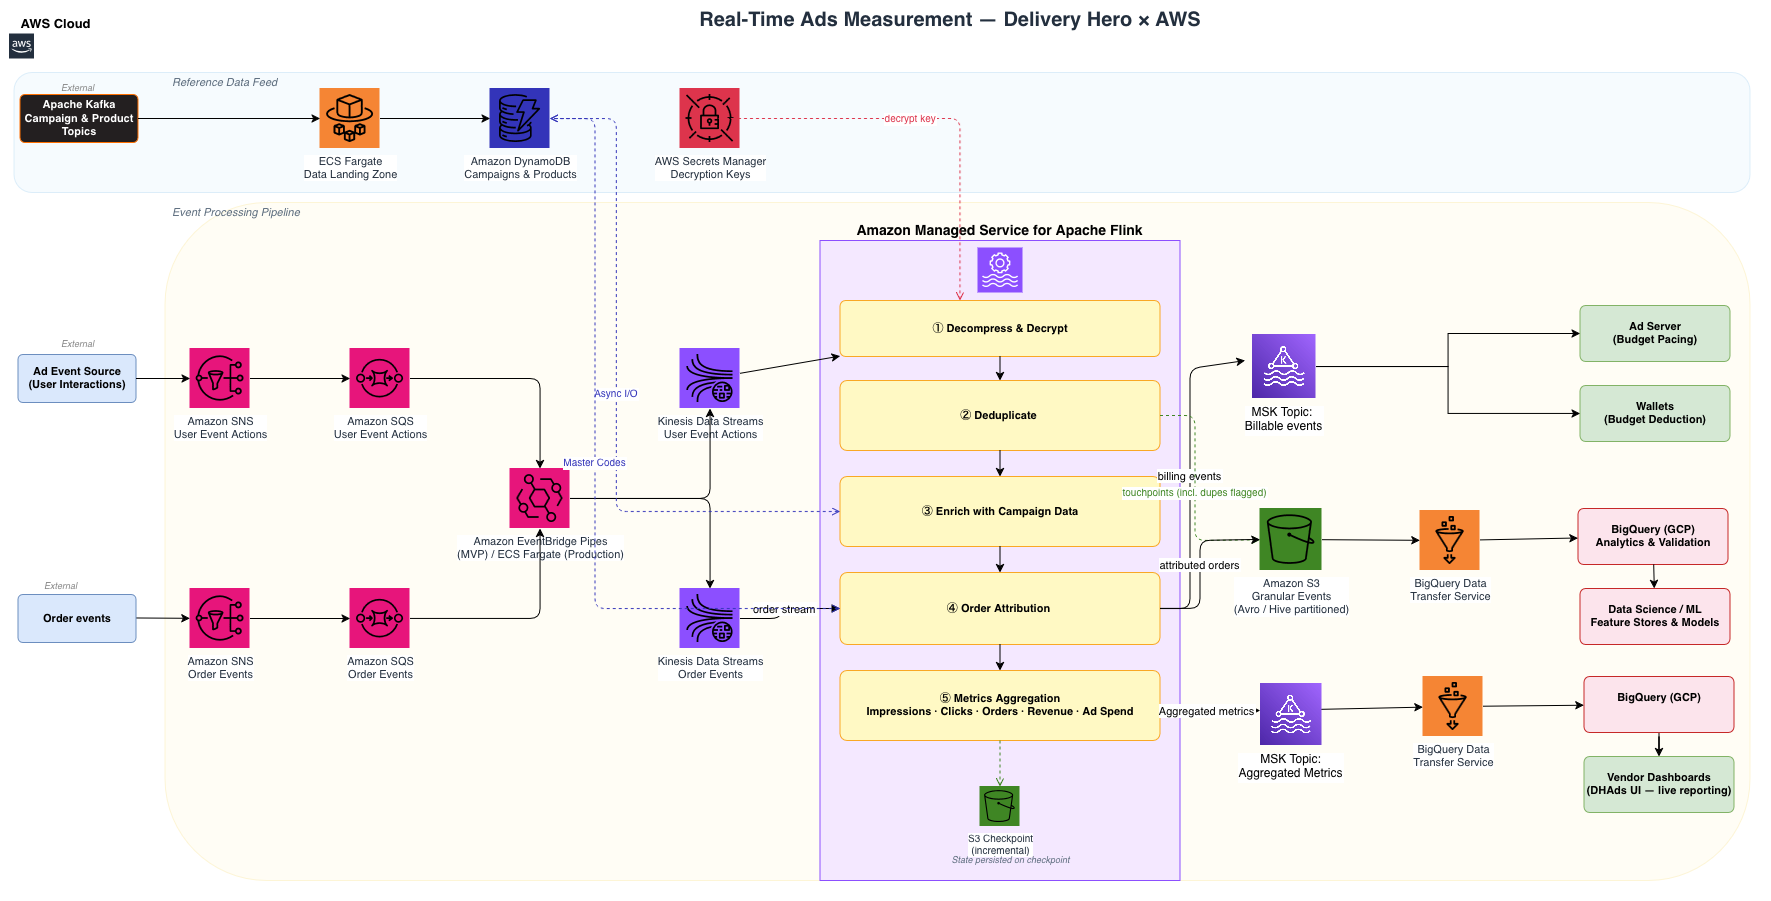
The following diagram shows the end-to-end pipeline.
Figure 1: End-to-end architecture of the real-time ad measurement pipeline
Two Amazon Simple Notification Service (Amazon SNS) topics ingest events: one receives user event actions (compressed, encrypted ad tokens containing campaign, vendor, and placement metadata), the other receives order events. Amazon SQS buffers both before Amazon EventBridge Pipes (MVP) or an AWS Fargate service (production) forwards them into Kinesis.
Amazon Managed Service for Apache Flink runs a five-stage Java pipeline:
Decompress and decrypt. The pipeline decrypts the ad event token using keys from AWS Secrets Manager.
Deduplicate. The pipeline keys events on a composite of entity, ad, event, and customer identifiers. Flink’s RocksDB state tracks seen events over a 30-hour window (approximately 20 GB of state), filtering duplicates while preserving them in Amazon S3 for audit.
Enrich. Flink’s Async I/O API queries Amazon DynamoDB concurrently for campaign metadata and product master codes, populated continuously from upstream Kafka topics by an AWS Fargate consumer.
Attribute. A multi-day keyed interval join matches user event actions to subsequent orders on entity, customer, vendor, and campaign dimensions (approximately 100 GB of state). This stage emits attributed orders to Amazon S3.
Aggregate. The pipeline accumulates impression, click, order, revenue, and ad spend metrics in RocksDB state, then batch-upserts them to the reporting database every 5 minutes.
The pipeline emits billing events (cost per mille (CPM) impressions and valid cost per click (CPC) clicks) to Apache Kafka topics. The ad server and budget service consume those topics in real time. Flink checkpoints all state incrementally to Amazon S3, so the job restores from the last checkpoint after a failure. Kinesis Data Streams and the upstream sources deliver at-least-once, and the deduplication stage in step 2 drops any event replayed during recovery. Billing is therefore effectively exactly-once, even though the transport underneath it is at-least-once.
Results and impact
The redesigned architecture achieved quantifiable performance gains across data fidelity, processing throughput, and operational expenditure, while introducing capabilities that were not feasible under the legacy model.
Processing latency: From hourly windows to real time
The average gap between when an event was published and when it was recorded dropped from 61 minutes to 1.2 seconds. Budget pacing and aggregated metrics now reflect activity within seconds rather than the following hour. Downstream ad serving and budget pacing systems act on real-time signals instead of reconciling after the fact.
Cost efficiency
The migration reduced monthly operational costs by approximately 57 percent, which more than halves the annual run rate for the pipeline. The saving came alongside stronger reliability, not at its expense.
System reliability
Durable attribution window. The multi-day attribution window lives in RocksDB-backed keyed state, roughly 100 GB on local TaskManager disks, checkpointed incrementally to Amazon S3. Per-key lookups stay in the low-millisecond range regardless of state size, and a crash or shard rebalance restores state from the last checkpoint rather than triggering a reconciliation job.
Elasticity replacing fragility. Async I/O against DynamoDB removed the synchronous enrichment chain that previously gated every event. The pipeline sustains 20,000 messages per second at peak without back-pressure leaking into ad serving or billing, and enrichment scales independently of ingestion. Flash sales and seasonal surges no longer threaten upstream systems.
Replayable history. The pipeline persists every raw event to Amazon S3 in Avro format the moment it lands, and Kinesis Data Streams retains the source stream for up to 7 days. When a logic bug surfaces or a downstream contract changes, the team reprocesses the affected time range deterministically against the original inputs. There is no bespoke backfill job and no reconciliation against external systems. Past data is a first-class input, not a frozen artifact.
Data quality at the source
The following table compares the three data quality gaps before and after the migration.
Metric
Before
After
Missing session rate
30–40%
0%
Missing customer IDs
5%
0.8%
Missing impression timestamps
91%
0.2%
Downstream applications now receive fully enriched transactional and session context. Machine learning models use session-scoped features for campaign ranking, conversion-rate estimation, and anomaly detection. The pipeline now computes those features from a complete event stream, rather than one in which roughly a third of events were missing session context and 91 percent of impressions were missing a reliable timestamp.
What’s next
The pipeline described here is the first of several planned migrations to Amazon Managed Service for Apache Flink. The team is extending the same architecture to additional ad formats, and connecting real-time Flink aggregations directly to the ad serving layer for sub-second budget pacing. The real-time data layer built for measurement also serves as the foundation for AI-driven use cases. The team plans to explore live user interaction streams feeding personalization ranking models and grounded large language model (LLM) recommendations, which were impractical with batch-oriented infrastructure.
Conclusion
Delivery Hero’s migration to Amazon Managed Service for Apache Flink shows that effectively exactly-once billing, multi-day stateful attribution, and manageable operational complexity are not competing goals. The combination that made it work: Kinesis Data Streams for ingestion, DynamoDB for low-latency enrichment, Amazon S3 for event storage and checkpointing, and Amazon EventBridge Pipes for rapid MVP delivery. Together they produced a system that is more accurate, more resilient, and less expensive than the one it replaced. For advertising platforms where billing accuracy and attribution correctness are commercial imperatives, this architecture offers a replicable path from batch approximation to real-time measurement.
On September 4, 2026, Oren Yomtov, a security researcher from Accomplish, responsibly reported a vulnerability affecting Cloudflare Containers and Cloudflare Sandboxes (which is built on Containers), through Cloudflare’s bug bounty program. Cloudflare has fully remediated the vulnerability, and we have no evidence that customer data has been compromised.
This post was prepared in collaboration with Oren Yomtov and the Accomplish security research team, whose detailed report and controlled testing helped us validate the issue and respond quickly.
Cloudflare Containers run workloads on multi-tenant infrastructure and automatically assign them to eligible servers; customers cannot select the underlying host. The researchers demonstrated that a customer with a Workers Paid account could recover residual disk blocks previously used by Containers on the same host. The technique could not target a particular customer, workload, host, or data, and residual data was not guaranteed to be present.
Cloudflare applied a fix across the Containers fleet, with no customer-side configuration changes required. Within the historical disk-I/O telemetry available to us, we identified no evidence of malicious exploitation. Activity we could attribute to the reported technique came from the researchers and Cloudflare engineers conducting authorized validation.
Here, we explain the underlying storage behavior, its potential impact, our investigation, and the actions we took in response.
How container storage allocation works
Cloudflare Containers use Linux device mapper thin provisioning (dm-thin) to provide each container with a writable root disk. Each container lives inside a dedicated virtual machine powered by the Firecracker virtual machine monitor. Firecracker presents this disk to the virtual machine as /dev/vdc.
Thin provisioning allocates physical storage only when a virtual disk writes to a previously unmapped region. The affected storage pools used a 64 KiB thin-block size. When the thin volume backing a container's root disk was deleted, its physical blocks were returned to a pool that served workloads belonging to multiple customer accounts.
The affected pool configuration included the following option:
skip_block_zeroing
With this option configured, dm-thin skips zeroing newly allocated blocks before making them accessible. Consequently, when a previously-used 64 KiB block was reassigned, a full-block write replaced its previous contents, but a smaller write changed only the written portion. The remainder could retain data from the block’s previous owner.
How the exploit worked
Reading an unmapped region of a new thin disk did not reveal residual data. For an unmapped region of the thin device, dm-thin returned zeroes without allocating a physical block.
The proof of concept identified 64 KiB-aligned regions corresponding to free space in the guest’s ext4 filesystem and wrote one aligned 4 KiB block into each region.
When such a write reached an unmapped thin block, dm-thin allocated a physical 64 KiB block from the shared pool. The 4 KiB write replaced only that portion of the block, and because block zeroing was disabled, the remaining 60 KiB could retain data from a previous container.
A subsequent raw-device read could therefore observe bytes that the new container had never written.
The proof of concept performed the following steps:
Create a container using a Workers Paid account.
Open the writable root disk at /dev/vdc.
Read the disk and record a baseline.
Write one 4 KiB block into each selected 64 KiB region corresponding to ext4 free space.
Read the resulting blocks again.
Examine only the portions not overwritten by the new container.
The submission included counts, block offsets, sizes, checksum results, and truncated hash prefixes. Although the researchers recovered raw blocks to validate the issue, the materials provided to Cloudflare contained no third-party filenames, identifiers, credentials, hostnames, addresses, or recovered content values. As described below, the researchers have also confirmed that they securely deleted the recovered data.
How the vulnerability was validated
The researchers used ext4 directory block checksums to distinguish blocks belonging to their own test filesystem created for the proof of concept from blocks originating from other filesystems.
When ext4 uses the metadata_csum feature, directory block checksums incorporate values associated with the filesystem and inode.
Across six production placements, the researchers reported:
All 5,614 testable directory blocks.
Zero of those blocks were attributed to the researchers’ filesystem.
2,700 distinct foreign directory inodes identified through checksum analysis.
To validate the method, the researchers tested it against blocks they had deliberately created and deleted in the controlled test filesystem used for the proof of concept. The method correctly attributed all 162 blocks to that filesystem.
The researchers ultimately observed residual material on 18 of 24 placements and 20 of 22 underlying nodes across four continents. The recovered block types included directory structures, database pages, and structurally complete SQLite databases. The researchers reported using scripts that output only aggregate counts and format checks, not recovered file contents. The materials submitted to Cloudflare contained no recovered content values or third-party identifiers. The researchers subsequently confirmed that recovered data under their control remained confidential and was securely deleted following submission, consistent with Cloudflare’s HackerOne disclosure policy.
Impact
The vulnerability would potentially have allowed for a customer with a Workers Paid account to recover residual data from storage blocks previously used by other customers’ Containers on the same underlying host.
A successful exploitation would have crossed the tenant-isolation boundary and could disclose filesystem metadata, directory structures, database pages, and application data.
However, an attacker could not select a particular victim or access an actively attached disk. Exposure depended on Cloudflare’s workload placement and which previously released blocks dm-thin reassigned. Moreover, the researchers did not demonstrate modification of another customer’s active data or impact to workload availability.
How we mitigated the vulnerability
Our first mitigation was to remove skip_block_zeroing from the dm-thin pool configuration across the fleet. This restored dm-thin’s default behavior of clearing newly allocated blocks before exposing them to a container. It stopped the reported technique, in which a small write triggered allocation and a larger read recovered residual data from the remainder of the block. The researchers independently confirmed that their proof of concept no longer worked after this change.
Zeroing new allocations did not sanitize blocks already mapped into existing thin devices. These mappings existed in running container disks and in each host’s cache of prepared dm-thin snapshots for OCI image layers. A new container could inherit mappings from a cached layer without allocating those blocks again, allowing residual bytes in unused regions, including ext4 free space, to remain readable through raw reads of /dev/vdc.
We therefore also retired all running container disks and removed cached image snapshots created before the mitigation. We drained hosts during off-peak hours, restarted the VMs on each host, and cleared each host's image cache so that disks and cached layers were recreated using zeroed allocations. We have completed this cleanup across the Containers fleet.
No evidence of exploitation
As part of our response, we investigated whether other workloads showed activity consistent with the reported exploitation technique. We reviewed retained historical disk-I/O telemetry from our container infrastructure, using the researchers’ proof of concept and our internal reproduction as reference activity.
The proof of concept produced a characteristic relationship between writes and reads. When a 4 KiB write reached a previously unmapped region, it could trigger allocation of a reused 64 KiB storage block. With zeroing disabled, the remaining 60 KiB could retain data from a previous container. Subsequent reads could therefore recover substantially more data than the new container had overwritten.
Using these characteristics, we developed detection signatures and applied them to the historical telemetry available to us. We identified activity attributable to the researchers and Cloudflare engineers conducting authorized validation, and did not identify additional activity consistent with the reported technique.
We saw no evidence that this specific attack vector was exploited by anyone else.
Cloudflare customers are protected
As we noted above, Cloudflare has patched this vulnerability and remediation does not require any further action by Cloudflare customers. In addition, we found no evidence of any malicious actor abusing this vulnerability.
Moving quickly with transparency
We thank Oren Yomtov and the Accomplish security research team for their thorough research, responsible disclosure, and collaboration on this post. We encourage the Cloudflare community to submit any identified vulnerabilities to help us continually improve the security posture of our products and platform.
We also recognize that the trust you place in us is paramount to the success of your infrastructure on Cloudflare. We take these vulnerabilities very seriously and will continue to do everything in our power to mitigate impact. We deeply appreciate your continued support and trust in our platform, and remain committed not only to prioritizing security in all we do, but also acting swiftly and transparently whenever an issue arises.
Timeline
September 4, 15:26 UTC: Oren Yomtov from Accomplish reported the issue through HackerOne.
September 4, 18:45 UTC: Cloudflare opened a security incident and confirmed the production setup that caused the flaw.
September 4, 21:27 UTC: Cloudflare merged the runtime fix and its reuse test.
September 4, 22:03 UTC: Cloudflare merged the changes for new and live pools.
September 4, 23:15 UTC: Cloudflare started rolling out the changes.
September 7, 06:13 UTC: Cloudflare completed rolling out the changes and began clearing old pool data.
September 14, 10:50 UTC: The researchers reported that their proof of concept had stopped working.
September 14, 12:52 UTC: Cloudflare awarded the researcher a bounty.
September 19, 15:03 UTC: Cloudflare completed cleanup of all pre-mitigation cached snapshots across the affected fleet.
Many of the transmissions sent over the radio spectrum can
be decoded with a relatively cheap hardware dongle. Thomas Eckert presented at
RustConf 2026 in Montreal about his hobby:
decoding radio transmissions with Rust.
In his presentation, he
covered all of the math necessary to get started with
software-defined radio,
and gave demonstrations of listening to AM and FM radio, as well as decoding
transmissions from
aircraft transponders. His slides and example code are
available on GitHub.
After a two-year hiatus, LWN’s Jonathan Corbet presented an updated edition
of his Kernel
Report at the Kernel
Recipes conference. Corbet looked at what is happening in the kernel
community, how it’s dealing with a period of accelerated change, and where
things might go in the future. Video of the talk is
available on YouTube for those who’d like to tune in.
Business Email Compromise (BEC) operates on a familiar playbook. Threat actors breach a mailbox, silently monitor operations, map approval chains, and ultimately exploit that access to divert funds or exfiltrate sensitive assets.
This dynamic is central to our analysis as we kick off a series around Rapid7’s collaborative research with Zimbra; upcoming installments will explore technical details and broader findings based within the Zimbra Collaboration Suite. Our investigation disrupted the traditional BEC model in unexpected ways. We uncovered over 50 vulnerabilities, and found that several allow attackers not just to observe environments, but to actively rewrite them by impersonating senders without credentials, controlling inbox visibility, and altering shared documents and calendars.
Business Email Compromise in action: Digital abuse of trust
None of this is theoretical for Zimbra. But don’t take my word for it, just ask Russia. CISA keeps putting Zimbra bugs into the Known Exploited Vulnerabilities catalog, and the last three years make the point on their own:
CVE-2024-45519, command injection in the postjournal service, unauthenticated command execution. Proofpoint saw attackers stuffing base64 payloads into CC fields on September 28, 2024. CISA added it to KEV on October 3.
CVE-2025-27915, stored XSS in the Classic Web Client, triggered by a crafted .ICS attachment. It is used as a zero-day against Brazilian military targets to steal mail and quietly set forwarding filters. It went into KEV in October, 2025.
CVE-2026-73570, unauthenticated command injection through SNMP notification handling. CISA added it on August 21 of this year and gave federal agencies three days. Shadowserver has been counting somewhere north of 260 compromised instances while hunting for exploitation artifacts.
Go back further and the pattern holds. Rapid7 tracked widespread exploitation of CVE-2022-27925 and CVE-2022-37042 in 2022, a path traversal chained with an authentication bypass that let attackers drop a JSP shell on a Zimbra server without credentials. Google’s Threat Analysis Group later documented four separate threat groups working the same zero-day known as CVE-2023-37580. Each of these groups went after email, credentials, and authentication tokens. Attackers figured out a long time ago that the system sitting in the middle of everyone’s communication is worth the effort. So when you find a set of bugs that let you write to that system instead of only reading from it, data theft stops being the interesting part.
Send an email as your CFO without ever touching their password, and you have the front half of a very convincing BEC. Keep control of the mailbox afterward and you have the back half, too. Here, the attacker has a strategic choice. They can delete the sent message to hide their tracks, effectively wiping the trail of the fraud OR they can choose to leave the message in the Sent Items folder. By doing so, they ensure the CFO sees ‘evidence’ of the email they supposedly sent, creating a gaslighting scenario where the victim is left questioning their own actions. Whether the attacker cleans up or leaves the trail, they are shaping the organization’s perception of reality. In the ensuing investigation, where Finance sees a sent request and the CFO sees no such activity, the organization is trapped in a conflict of evidence. At that point, BEC looks less like traditional fraud and more like a psychological operation.
Documents make it worse, as Zimbra is not just a mail server. The collaboration side holds the files employees actually use to make decisions. An attacker who can plant a fake HR memo or financial summary in an executive’s enterprise drive, and make it look like it came from a peer they trust, is starting from a much better position than someone attaching a PDF to a cold email.
Say a document shows up from HR about a confidential restructuring, and a few days later an email from a trusted executive references it. Neither piece has to carry the whole deception, as each one props up the other.
Calendar warfare and manufactured enterprise reality
Then there is the thing I have started calling ‘calendar warfare.’ Meetings can be modified or deleted without generating the notification trail users expect to see. RSVP status can also be flipped. Maybe a key executive is changed from Accepted to Declined and leadership might reschedule, or move ahead without them, or read the whole thing as a deliberate opt-out.
It works in the other direction too. An “Emergency Board Meeting” lands on an executive’s calendar with a believable organizer, a popup reminder, and a malicious Zoom link. When the reminder fires, the victim is not sizing up a suspicious email that arrived thirty seconds ago. They are joining a meeting that has been sitting in their calendar for two days. And the calendar is not some exotic attack surface nobody has thought of. If we look back at CVE-2025-27915, the delivery vehicle was a calendar invite.
Stack all of it together now – a financial document appears, a trusted executive emails about it, then a mandatory meeting shows up to discuss it. And the attacker still has the ability to clean up some of what gets left behind. Every artifact the victim checks lives inside a system they have no reason to question, and all of them tell the same fabricated story.
I keep coming back to the phrase ‘manufactured enterprise reality‘. I have touched on the idea in The Monday Brief, that attackers get to borrow whatever trust an organization has already extended to its own tooling. Zimbra makes it concrete. The platform supplies the credibility, so the attacker does not have to build any.
Collaboration suites quietly became systems of record. Email is the record of who said what. Calendars are the record of who agreed to be where. Classic BEC abuses the trust between two people. The scenario we’ve discussed here abuses the machinery those people use to decide who to trust in the first place. Once employees are making real business decisions off fabricated context, stealing data is the least of your problems.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.