New Research: We’re Still Terrible at Passwords; Making it Easy for Attackers

Post Syndicated from Tod Beardsley original https://blog.rapid7.com/2022/10/20/new-research-were-still-terrible-at-passwords-making-it-easy-for-attackers/
New Research: We’re Still Terrible at Passwords; Making it Easy for Attackers

Passwords, amirite? We all have them. Probably a lot of them. And they are among the most important lines of defense against nefarious attackers seeking access to our online accounts. Sadly, as we all know too well, password health isn’t exactly our collective strong suit and too often we hear about breaches coming from loosely or poorly managed passwords.

At Rapid7, we are constantly conducting original research into the latest trends in attacker behavior, vulnerabilities, and cyber security trends that could lead to the next big breach (or the next big goal line save). In our latest report, Good Passwords for Bad Bots, we took a look at two of the most popular protocols used for remote administration, SSH and RDP, to get a sense of how attackers are taking advantage of weaker password management to gain access to systems. What we found in many ways confirmed our assumptions 1) attackers aren’t “cracking” passwords on the internet; and 2) we still collectively stink at password management.

Here’s how we did it.

As a cybersecurity company we are sometimes called upon to dabble in the “dark arts” in order to better prepare ourselves and our customers for the types of attacks they can expect to see in the real world. Sometimes that means penetration testing (hire us to hack into your systems, trust us, it’s fun). And sometimes we deploy honeypots to entice and capture behavior of attackers in a risk-free environment in order to study them.

For this report, we used our network of honeypots (a few hundred of them) to monitor SSH and RDP login attempts. Once we zeroed in on authentication attempts (as opposed to vulnerability exploit attempts, low-touch scans, and the like) we found 512,002 unique passwords were attempted to be used by attackers.

We then turned to the rockyou2021.txt list to determine how many of those passwords existed in this industry-standard list of exposed passwords. Prepare to be shocked: nearly all of them were. In fact, we found just 14 of the passwords being brute forced into our honeypots were NOT found in the rockyou2021.txt file. And we think those were likely errors as they included a string of the honeypots’ IP addresses in them. Unless they are signs of some dastardly attack that we haven’t seen before <cue dramatic music> they are likely insignificant.

But if attackers were using automated tools to “crack” passwords online we’d see more of them, a lot more. There are something to the tune of 8.4 billion passwords on the rockyou2021.txt file. We found less than half a million in our honeypots. What’s more likely to happen is attackers still rely on the human connection to security infrastructure which is notoriously one of the weakest links in the chain. Social engineering, like phishing for passwords, and credential stuffing (ie. trying known passwords across other targeted platforms to catch someone reusing identical usernames and passwords) are still stronger ways for attackers to gain access to passwords than cracking them automatically.

What this tells us in practicality is that it’s not terribly hard to avoid this class of attack. In fact, some of the most attacked credentials were ones that should make any internet-literate person facepalm hard. The three most popular user names for RDP were “administrator,” “user,” and “admin.” The three most common passwords? Brace yourselves: “root,” “admin,” and “nproc.” One of the most popular passwords was literally “123456” which is definitely not the combination to our luggage. So, yeah, we’re not doing well enough with our passwords.

But as we said earlier, it’s not that hard to beat this kind of attack. You don’t even have to have a particularly strong password in order to protect yourself, just one with randomness in it. Maybe throw in a few strange characters. Don’t reuse it for multiple logins. And above all don’t use default passwords. All of these things would be covered by the use of password manager services that create unique, random passwords for every one of your online accounts. We’re not getting paid by these services to say this, I assure you, they just happen to be a strong but underutilized way to have good credential hygiene.

If you want to learn more, download our new report Good Passwords for Bad Bots. And then, go change your passwords. All of them. You’ll be glad you did.

Без важничене. Разговор с Йордан Д. Радичков

Post Syndicated from Стефан Русинов original https://toest.bg/yordan-d-radichkov-interview/

Йордан Д. Радичков е автор на четири сборника с разкази: „Малка човешка мелодия“ (2015), „Игра на гъски“ (2016), „Двеста линейки на час“ (2018) и „Навалица! Или 25 часа в град София“ (2022). Последният беше отразен в рубриката „По буквите“ от Зорница Христова, която междувременно предложи Стефан Русинов да проведе разговор с автора. Според Стефан идеята ѝ е хрумнала, защото той е „сред малкото хора, които не уважават достатъчно собственото си време и са чели всичките споменати сборници“. Но аз подозирам, че е по-скоро заради невероятно задълбоченото му интервю с Йордан за „Нашето литературно предаване“ преди няколко години. 

„Дори ще ви оставя да се полигавите“, казах на Стефан, за да го убедя. И така двамата започват да водят този разговор по имейл, кореспонденцията продължава десетина дни и ето го резултата. Не познах, не са се полигавили. Преди всичко защото отвъд „дрънкането“ и привидния небрежен келешлък тези двама млади и талантливи хора на словото могат да бъдат много, много сериозни. А и „думите никога не са маловажни“, както казва Йордан в интервюто.

Ан Фам


Click to view slideshow.

Щом човек го поканят на интервю, изведнъж почва да му се струва, че има разни много важни неща за казване.

Щом човек го поканят на интервю, той мигновено започва да важничи. Ние с тебе хора ли сме и важничим ли, когато ни поканят на интервю? Естествено! Някой ни е обърнал внимание и искаме да се представим в най-чудесна светлина. Има и друг момент – форматът като че ли е такъв и често въпросите, които ни задават, сами по себе си важничат. Разбираш ли ме? Самите въпроси започват да се докарват пред самите себе си и да се превъзнасят. Често се стига дотам, че те настояват да бъде разбродирана самата материя на света и да се отговори на невъзможни неща – какво представлява човекът и какъв е смисълът на съществуването.

Забеляза ли как започнах и аз да важнича? И може би от тези натрупвания има едно такова разбиране, че задължително трябва да се каже нещо важно. Лично за себе си не смятам, че имам да кажа нещо твърде важно. Също така, освен да се чувства задължен да казва важни неща, интервюираният задължително трябва и да скромничи и кокетничи. И това може би е върхът на важниченeто. Защото и аз, и ти в момента се правим на много интересни, затова ти предлагам да спреш с глупостите и да караме по същество.

На тебе са ти поръчали (искам да подчертая тая дума, тъй като сам ти не си имал желание да си говорим, а са ти поръчали този разговор) да си говориш с мене, аз съм приел да си говорим. Затова сме длъжни, от уважeние към хората, които ще си загубят времето да четат нашите глупости (пак кокетничене и скромничене), да проведем един открит разговор, пък накрая ще стане ясно имали ли сме да кажем нещо важно!

И да завърша все пак с един цитат: „Разбира се, защото интервюираният човек струва много повече от човека, дето не е интервюиран. Познавах едного, той не бе интервюиран и трябва да Ви кажа, че беше нищо човек. Добре, ама един ден му излезе късметът, интервюираха го и след като го интервюираха, той много се издигна и стана значителен човек. Затова всеки гледа да го интервюират.“

Впрочем твоите разказвачи усилено избягват да важничат. Те често отбелязват с разбиране как хората са потънали в „някаква си тяхна работа“, допускат, че никой не иска да се занимава с техните или с които и да е чужди глупости, понякога им се струва, че сякаш никой не забелязва, че „не е сам в цялата тая работа“. Примирени са с липсата на интерес, съзнават маловажността на думите си, но въпреки това разказват, настояват да поглеждат извън себе си, извън „своята си работа“. За мен е важен този глас на разказвача, който не смята, че някой изобщо му дължи внимание. 

Не мисля, че бягат, не мисля, че избягват, просто знаят, че от подобна суета полза няма. Именно че може би притежават някакво разбиране за „цялата работа“, тоест разбирането, че хем сме сами, хем непрестанно сме заедно, хем не можем да настояваме някой да ни обърне внимание, когато всички заедно сме сами, и често ни е трудно да се справим с предизвикателствата и фрустрациите на собствения си живот. Как можем да настояваме за нещо от човека до нас, когато познаваме този човек и виждаме колко и на него му е трудно?

Не смятам и че са примирени, те просто виждат и разбират сложнотията на ежедневието, което всеки ден ни удря по муцуните и настоява да се борим с него. И не че думите им са маловажни, не че нашите думи са маловажни. Не мисля, че има маловажни думи. Има дрънкане със сигурност, но сами по себе си думите никога не са маловажни. И как да не продължават да разказват и да говорят, когато именно в разказването и говоренето се крие животът ни.

Виж, не се опитвам да важнича, опитвам се да ти отговоря конкретно точка по точка на въпросите, които засягаш. Но със сигурност никой нищо не ни дължи. Полага ни се нещо, когато съществува някаква транзакция. Предполагам, че ни се полага адекватно здравеопазване и така нататък. Но в човешките взаимоотношения може би е деградивно и даже опасно да се говори за нещо, което се дължи.

Това тяхно разбиране за „цялата работа“, този малко по-отдръпнат и по-висок поглед обаче не ги изключва от дереджето. Една от най-удовлетворителните (и подривните) особености на тяхната разказваческа настройка е, че за човешките слабости и абсурди говорят най-често в първо лице множествено число: „Ами да! Нима нашето съществуване не превъзхожда всички останали съществувания? Нима нашата работа не е по-спешна и не е по-важна! И нима ние не сме твърде интелигентни, за да се занимаваме с подобни тривиалности, като задръствания? Ама ако всички сме толкова интелигентни, че да не се занимаваме с подобни задръствания, защо всички сме се емнали в задръстването да правим още по-голямо задръстване?“

Да, не ги изключва, и нас не изключва. Можем ли да съществуваме изолирани от всичко, ама всичко, което е около нас? Можем ли да настояваме, че ще успеем да наредим една градина по средата на целия свят, който ври и кипи, и ще посадим в тази градина невъзможно красиви цветя? И наистина ли можем да повярваме, че каквито и огради да вдигаме около нашата градина, те никога няма да бъдат прескочени от никого и никога никой няма да посегне на нашите цветя, никой никога няма да ги откъсне и стъпче? И нима, когато това се случи, ние ще сме изненадани?

Предполагам, че можем да говорим безкрайно за настояването ни, че ние все някак ще сме си добре, независимо от всичко, което е около нас. Но то винаги ще е част от нас, то съществува вътре в нас също и може би нежеланието ни да го погледнем е от страх и чувство за немощ. Затова и на мен ми харесва, че героите винаги говорят в това лице и число, защото така ни напомнят, че ние всички сме такива, ние всички сме избродирани от безчетно много слабости, и макар да ни е неприятно да говорим за тях, струва ми се, че е по-добре да ги адресираме навреме. Ако не се погрижим за една рана навреме, тя само ще се задълбочи.

Както казва твоят персонаж Кларинета: „Сивотата на човека е тъжна работа.“ Може би това е причината разказвачите ти да не са склонни да поставят прибързани граници между себе си и другите, независимо дали живеят в просторна къща, или в малък апартамент, дали спят върху възглавница от гъши пух, или върху изрязан дунапрен – защото далеч по-важни от тези повърхностни признаци са сивотите, неподозираностите, подводните чудовища, които ни обединяват „в дълбините на нашите съзнания“. Ето още една „работа“, която някои от твоите разказвачи наблюдават внимателно – неведомите вътрешни светове. 

Тъжна работа е, естествено! Но е част от нас и ми се струва, че е хубаво да не забравяме това, когато имаме друг човек пред себе си. Струва ми се, че повечето ужасяващи явления, които ни заобикалят, са пряко свързани с тази сивота, с тази тъга и този страх. И ако се търси в дълбочина причината за подобни явления, именно там ще я намерим. Когато не обръщаме внимание на тези неприятности, които са толкова естествени, ние като че ли не обръщаме внимание на човека срещу нас. Ние така го пренебрегваме и така пренебрегваме и себе си. Не казвам, че трябва да заровим муцуна в дълбините на нашите съзнания (боже, само как звучи!), но се надявам да не оставаме слепи за тях.

Може би това е нещо, което само литературата може да прави, или поне може да прави доста добре – да осветява слепите ни петна, да се завира в мътните ни дълбини, да ни посочва реалността, която не виждаме. И най-важното – да ни напомня за възможността човешкото в нас да се изчерпи, опасността човек да се превърне във функция.

Дано не се превърнем в прости функции, прости дроби и прости числа и дано не гледаме на хората около нас като на функции, продавачи, шофьори и чистачи!

Снимки: © Йовко Ламбрев

Източник

Краят на парламента започна с началото му

Post Syndicated from Емилия Милчева original https://toest.bg/krayat-na-parlamenta-zapochna-s-nachaloto-mu/

„Ама като хванем гьостерицата“, изокаха в социалните мрежи след провала на 48-мия парламент да избере председател в първия работен ден. Все едно какъв изход ще намерят днес депутатите, всички те вкупом орезилиха парламентаризма. Скорошни предсрочни избори вече са съвсем реални, а предизборната кампания не е спирала.

Нито една от първите две политически сили, които по конституция имат право на мандат за съставяне на правителство и дават заявка, че искат да управляват – ГЕРБ и „Продължаваме промяната“, не успя да осигури мнозинство, за да наложи кандидата си. Противоборството между тях изглежда непреодолимо, противоречията между публичните им изявления и реални действия – ослепителни.

От една страна, ГЕРБ, първи след изборите на 2 октомври, изявиха намерение да преговарят с ПП и „Демократична България“, от друга – не спират да бичуват „Промяната“ за резултатите от управлението им. От една страна, ПП си избраха ролята на „конструктивна опозиция“, от друга – няма да откажат да съставят правителство с втория мандат, ако първият се провали (което не подлежи на съмнение).

Изпреварващ ход

Изненадващо на брифинг късно снощи от ПП оттеглиха своя кандидат за председател на НС Никола Минчев с мотива, че са „конструктивна опозиция“ – и няма да подкрепят кандидат на ГЕРБ. След като видели, че никой от претендентите няма нужните 121 гласа, ПП не искат да вкарват страната в конституционна криза. „Даваме стъпка назад“, обясни Асен Василев. Стъпката назад не помага особено за стъпка напред в избора на председател на 48-мия парламент. Тя обезсмисля предложението на ДБ Желязков и Минчев да управляват парламента на ротационен принцип, което единствено ГЕРБ посрещнаха с решение да го подкрепят, но не получиха одобрение нито от ПП, нито от БСП.

Сега остава вариантът да бъде избран представител на някоя от по-малките политически сили – Кристиан Вигенин, който е вече предложен от БСП, но не събра необходимото мнозинство, или кандидат, издигнат от ДБ. Съществува и хипотезата ДПС и „Български възход“ (БВ) да подкрепят Желязков – не без съучастието на „Възраждане“. Но вчера ДПС, които подкрепиха ГЕРБ в първата процедура, за втората номинираха свой кандидат – Йордан Цонев. Техният политически нюх може и да им е подсказал да не залагат на куц кон, тъй като ГЕРБ са в явна изолация, и да се ориентират към други залози.

Лагерите

В осемте часа на първото заседание (де юре неприключило) се очертаха и различни мнозинства, които затрудняват още повече този обречен парламент, тъй като зануляват надеждите да свърши нещо повече от приемането на бюджета за догодина.

Едно такова мнозинство оформят президентът Румен Радев, БСП и „Възраждане“, също и БВ. Те настояват България да се въздържа от подкрепа за Украйна, развявайки тези за „войнолюбци“, някакъв ефимерен мир и неутралитет. „Голямата задача пред политическата класа днес е да опазим България от пожара, който бушува. Българските избиратели и историята няма да простят на онези, които поради лекомислие или корист тласкат страната във войната“, заяви държавният глава в словото си, изразявайки надежда подобни „войнолюбци“ да бъдат малцинство в парламента. „Възраждане“ не изневерява на реториката си, наричайки „евро-атлантическа тълпа“ депутатите, които ще „вкарат във война“ България. А „националните консерватори“ от БВ просто игнорираха темата за руската агресия в Украйна. За същото това мнозинство не е приоритет и еврозоната.

Следвайки евро-атлантизма като червена линия, от другата ѝ страна са ДБ и ПП, както и ГЕРБ и ДПС. Но в този лагер евро-атлантизмът е нюансиран – за първите две политически сили е неразделно свързан със съдебна реформа и очистване на българските институции от руско влияние и корупция. Възможностите за руско влияние следват от корупционната разруха на българските институции, заяви в пленарната зала съпредседателят на ДБ Христо Иванов.

За другите две партии не е баш така – разбира се, Десислава Атанасова (ГЕРБ) назова „борбата с корупцията“ и „правосъдната реформа“ като приоритети на партията, но толкоз – просто необходими клишета. Лидерът на ДПС Мустафа Карадайъ изобщо не ги назова, затова пък беше ясен по темата за евро-атлантизма като обективна необходимост: „България е член на НАТО и България трябва да продължи своето евро-атлантическо развитие, и всички ние тук трябва да сме част от този процес. Нямаме друга алтернатива, членове сме на НАТО и ЕС и точка по въпроса.“ Сходна, но не така членоразделна позиция споделя и председателят на „Български възход“, който лаконично отбеляза да не отправяме призиви за излизане от съюзи, а „ясни послания с изправен гръбнак“ към съюзниците.

Големият вододел

„Заплахата от войната в Украйна не трябва да притъпява нуждата от законност в България. Няма как да си евро-атлантик, ако не уважаваш върховенството на закона, не държиш на работеща, реформирана съдебна система и не отстояваш премахването на корупцията по всички етажи на властта“, заяви от парламентарната трибуна съпредседателят на ПП Кирил Петков.

Христо Иванов беше съвсем ясен, повтаряйки, че реформата на прокуратурата и ВСС е условие на коалицията му за подкрепа на кабинет. А по повод Украйна той казва: „Не може да си затваряме очите за тази война. Не може, като кажем, че България е за мир, да очакваме, че мирът ще настъпи, че мирът ще се кондензира като роса. Замитането на войната под килима, да се твърди, че България може да е като Северна Корея на Балканите, не е въпрос дали си войнолюбец, или не, а е въпрос дали се разбира каква е реалната ситуация.“

ДБ внесе вчера проекторешение за военна помощ за Украйна, в което фигурират и консултации със съюзниците от Алианса за предоставяне на заместващо въоръжение и „всеобхватна програма за въоръжаване на българската армия“. (За последното настояват и президентът, и служебният министър на отбраната Димитър Стоянов.)

За „Възраждане“ и „Български възход“ темите за корупцията и върховенството на закона липсваха. Лидерът на БВ отправи някакво мъгляво послание в речта при откриването на парламента за някакви 10–15 личности, на които трябвало да се направи одит, но без да спомене думата „корупция“, камо ли „реформа на прокуратурата“.

„Справедливостта изисква редът и правилата да се спазват от всички. В същото време в обществото ни има 10–15 личности, които ни разделят и поляризират, личности, чиято репутация е в основата на разделителни линии и липсата на диалог. Ние ще работим за създаване на механизъм за одит на дейността на тези хора, който или да завърши с обвинения, или да спрем отровата и злобата в ежедневието си“, заяви Янев.

В декларацията на БСП всичко се изчерпи с една-единствена фраза (също като при ГЕРБ) за „безкомпромисна борба с корупцията“.

Колко да е безкомпромисна

Това е истинското мнозинство в парламента – на мълчащите за корупцията и безконтролната власт на главния прокурор, като ДПС, „Възраждане“ и „Български възход“, и на формалистите за битката с тях, като ГЕРБ и БСП. Подобно мнозинство провали първия опит за истинска съдебна реформа. Вторият опит тепърва предстои – и в словото си президентът напомни, че е неизбежен поради факта, че е предвиден в Плана за възстановяване и устойчивост (ПВУ):

„… очаквам те [проектозаконите за ПВУ] да бъдат разгледани и приети в спешен порядък. Не само заради очакваното финансиране, а най-вече заради ролята на тези закони за отключването на важни и дългоочаквани реформи – за укрепване на държавността, утвърждаване на върховенството на правото, борбата с корупцията по високите етажи на властта и фактическата недосегаемост на главния прокурор, за цялостна модернизация на икономиката и страната.“

Става въпрос за антикорупционния проектозакон, който включва и преструктурирането на КПКОНПИ, и за законопроект за отчетност и контрол на прокуратурата и главния прокурор. И двата са ключови, за да бъдат получени средствата по ПВУ, а според заложените срокове законопроектът за прокуратурата трябва да е приет и обнародван до юни догодина. Опциите са реформите да бъдат смачкани още в този парламент – или надеждите за същински промени да се възложат на 49-тия парламент, в навечерието на местни избори.

Главният прокурор Иван Гешев, разбирайки, че промените са неминуеми, пое инициативата в свои ръце и тази седмица разпрати писма до депутатите, в които призовава за спешна правосъдна  реформа, овладяване на престъпността и диалог с институциите. С аргументи, че се рушат устоите на държавността и демократичните стандарти, Гешев очаква депутатите да се заемат „незабавно и отговорно“ с проблемите на правосъдната система. Ход, който на пръв поглед показва диалогичност, но също така издава и страх, и пореден опит да брани своята неуязвимост – също и на тези, чието куче пазач е.

Вчера пред bTV Даниел Лорер (ПП) определи като „терапевтично“ първото заседание, защото излезли конфликтите. Това да не му е семейна констелация, където разкриването на фамилните драми действа оздравително? В политиката конфликтите остават до разрешаването им чрез преговори, подкупи или чрез битка до победа/загуба на единия от противниците.

Докато траеха парламентарните гърчове, лидерът на ГЕРБ Бойко Борисов играеше в мача на ветераните между „Витоша Бистрица“ и ЦСКА 1948, спечелен от отбора му с 4:0. Във футбола още му върви.

Заглавна снимка: © Светла Енчева

Източник

Резюме на първия парламентарен ден

Post Syndicated from Bozho original https://blog.bozho.net/blog/3961

За следящите с половин ухо парламентарните драми, нека обясня какво се случи вчера.

По Конституция на първото заседание трябва да бъде избран председател на Народното събрание. 4 партии бяха заявили, че ще издигнат кандидат – ГЕРБ (Росен Желязков), ПП (Никола Минчев), БСП (Крисриян Вигенин) и Възраждане (Петър Петров).

Процедурните правила, ползвани в предишни парламенти, бяха внесени и сега и предвиждат ако никой не събере повече от половината гласове, двамата кандидати с най-много да отидат на балотаж, и там който е събрал повече – става председател.

На балотажа Желязков събра 103 (ГЕРБ и ДПС), Минчев 97 (ПП, ДБ и БСП). Възраждане и Възход се въздържаха. Обаче Конституцията не позволява решение с по-малко от 50%+1, така че избран председател нямаше.

Трябваше да се направи втора процедура, около която имаше дебати. ГЕРБ казваха на ПП „Вие хем искате да се опозиция, хем да имате председател“, казваха на ДБ „вие защо не ни подкрепите, за да тръгне това Народно събрание, оставете ги тия ПП“.

Ние на това отговорихме, че изборът на председател е сигнал за формиране на мнозинство, а ние с ГЕРБ мнозинство няма да формираме и затова няма как да очакват подкрепа.

Изборът се повтори (на втория път ДПС издигнаха Йордан Цонев), но логично никой нямаше 121 гласа. Така се оттеглихме на почивка за вечерта, а заседанието ще продължи днес.

В ДБ се събрахме и отчетохме реалностите – мнозинство няма и съответно никой не може да има председател, ако следваме трайната политическа логика. Липсата на председател, обаче, блокира парламента. Първото засесание не може да приключи и нищо друго не може да бъде гласувано.

А тъй като дори без кабинет, НС трябва да гласува важни неща – бюджет, закони по Плана за възстановяване, в т.ч. за разследване на главния прокурор, не може просто да се саморазпуснем. А и ще излгежда несериозно и ще срине допълнително доверието в парламентарната демокрация.

Затова в този блокаж обмислихме как да действаме и предложихме ротационно председателство (такова има в Европейския парламент, а механиката как да стане това у нас няма да я обсъждам тук, но тя включва както официални решения на НС, така и разбирателство, обявено пред хората, което никой няма интерес дс наруши).

Такъв подход прескача темата за мнозинствата, каквито няма. Решава техническия въпрос, без да сме избрали председател нито от ГЕРБ, нито от ПП, макар формално един от двамата в даден момент да бъде с функцията на председател и има позитивния аспект, че най-големите партии ще са начело.

Заедно с решаване на техническия въпрос, можем да вземем решение за бързо формиране на комисии, приоритизиране на законопроекти, деприоритизиране на други (напр. че няма да се връща хартията в Изборния кодекс) и да започнем работа по това, за което са ни избрали.

Снощи ПП оттеглиха Никола Минчев, което допълнително ще покаже и затвърди това, което отвътре беше очевидно вчера – дори само Желязков да беше кандидат, ГЕРБ нямат мнозинство. На практика ще зависят от Възраждане, но те едва ли биха подкрепили нещо различно от своя кандидат.

Надявам се след това да влезем в алтернативни, „технически“ сценарии за избиране на председател, за да разблокираме парламента. Нашето предложение е един такъв вариант, но има и други. Плюсът е, че липсата на мнозинство предполага, че никой няма монопол над дневния ред.

Фрагментираният парламент изисква разговори, но не необявени договорки. Изисква компромиси, но не в нарушение на принципи. Но можеше да спестим вчерашния ден на българските граждани. ГЕРБ знаят, че нямат мнозинство и вместо да са назидателни от трибуната, можеше днешните предстоящи разговори да са се случили онзи ден, а вчера да обясним на хората, че тъй като в обичайната хипотеза не можем да изберем предсесател, за да отключим работата на парламента, предлагаме определен компромис.

Предстои ден втори от първото заседание на може би най-трудния парламент в новата ни история.

За следящите с половин ухо парламентарните драми, нека обясня какво се случи вчера.

По Конституция на първото заседание трябва да бъде избран председател на Народното събрание. 4 партии бяха заявили, че ще издигнат кандидат – ГЕРБ (Росен Желязков), ПП (Никола Минчев), БСП (Крисриян Вигенин) и Възраждане (Петър Петров).

Процедурните правила, ползвани в предишни парламенти, бяха внесени и сега и предвиждат ако никой не събере повече от половината гласове, двамата кандидати с най-много да отидат на балотаж, и там който е събрал повече – става председател.

На балотажа Желязков събра 103 (ГЕРБ и ДПС), Минчев 97 (ПП, ДБ и БСП). Възраждане и Възход се въздържаха. Обаче Конституцията не позволява решение с по-малко от 50%+1, така че избран председател нямаше.

Трябваше да се направи втора процедура, около която имаше дебати. ГЕРБ казваха на ПП „Вие хем искате да се опозиция, хем да имате председател“, казваха на ДБ „вие защо не ни подкрепите, за да тръгне това Народно събрание, оставете ги тия ПП“.

Ние на това отговорихме, че изборът на председател е сигнал за формиране на мнозинство, а ние с ГЕРБ мнозинство няма да формираме и затова няма как да очакват подкрепа.

На изказванията на ДПС, че такава била традицията – да се избира председател от най-голямата партия, отговорът е, че такава ситуация е нямало, че да има традиция. Имало е управляващо мнозинство без първия (2013) и „опозиционно мнозинство“ (2021). Но сега ме сме в нито една от тези хипотези.

Изборът се повтори (на втория път ДПС издигнаха Йордан Цонев), но логично никой нямаше 121 гласа. Така се оттеглихме на почивка за вечерта, а заседанието ще продължи днес.

В ДБ се събрахме и отчетохме реалностите – мнозинство няма и съответно никой не може да има председател, ако следваме трайната политическа логика. Липсата на председател, обаче, блокира парламента. Първото засесание не може да приключи и нищо друго не може да бъде гласувано.

А тъй като дори без кабинет, НС трябва да гласува важни неща – бюджет, закони по Плана за възстановяване, в т.ч. за разследване на главния прокурор, не може просто да се саморазпуснем. А и ще излгежда несериозно и ще срине допълнително доверието в парламентарната демокрация.

Затова в този блокаж обмислихме как да действаме и предложихме ротационно председателство (такова има в Европейския парламент, а механиката как да стане това у нас няма да я обсъждам тук, но тя включва както официални решения на НС, така и разбирателство, обявено пред хората, което никой няма интерес дс наруши).

Такъв подход прескача темата за мнозинствата, каквито няма. Решава техническия въпрос, без да сме избрали председател нито от ГЕРБ, нито от ПП, макар формално един от двамата в даден момент да бъде с функцията на председател и има позитивния аспект, че най-големите партии ще са начело.

Заедно с решаване на техническия въпрос, можем да вземем решение за бързо формиране на комисии, приоритизиране на законопроекти, деприоритизиране на други (напр. че няма да се връща хартията в Изборния кодекс) и да започнем работа по това, за което са ни избрали.

Снощи ПП оттеглиха Никола Минчев, което допълнително ще покаже и затвърди това, което отвътре беше очевидно вчера – дори само Желязков да беше кандидат, ГЕРБ нямат мнозинство. На практика ще зависят от Възраждане, но те едва ли биха подкрепили нещо различно от своя кандидат.

Надявам се след това да влезем в алтернативни, „технически“ сценарии за избиране на председател, за да разблокираме парламента. Нашето предложение е един такъв вариант, но има и други. Плюсът е, че липсата на мнозинство предполага, че никой няма монопол над дневния ред.

Фрагментираният парламент изисква разговори, но не необявени договорки. Изисква компромиси, но не в нарушение на принципи. Но можеше да спестим вчерашния ден на българските граждани. ГЕРБ знаят, че нямат мнозинство и вместо да са назидателни от трибуната, можеше днешните предстоящи разговори да са се случили онзи ден, а вчера да обясним на хората, че тъй като в обичайната хипотеза не можем да изберем предсесател, за да отключим работата на парламента, предлагаме определен компромис.

Предстои ден втори от първото заседание на може би най-трудния парламент в най-новата ни история.

Материалът Резюме на първия парламентарен ден е публикуван за пръв път на БЛОГодаря.

В центъра на София посред бял ден: Топ финансист и бивш банкер рекетира и преби вносител на електронни цигари

Post Syndicated from Екип на Биволъ original https://bivol.bg/%D1%82%D0%BE%D0%BF-%D1%84%D0%B8%D0%BD%D0%B0%D0%BD%D1%81%D0%B8%D1%81%D1%82-%D0%B8-%D0%B1%D0%B8%D0%B2%D1%88-%D0%B1%D0%B0%D0%BD%D0%BA%D0%B5%D1%80-%D1%80%D0%B5%D0%BA%D0%B5%D1%82%D0%B8%D1%80%D0%B0-%D0%B8.html

сряда 19 октомври 2022


Бившият топмениджър на ЗК „Армеец“ Румен Георгиев е участвал в насилие, изнудване и пребиване на предприемач. Случаят е станал на 3 октомври 2022 г. в офиса на фирмата му „Логос…

AWS successfully renews GSMA security certification for US East (Ohio) and Europe (Paris) Regions

Post Syndicated from Janice Leung original https://aws.amazon.com/blogs/security/aws-successfully-renews-gsma-security-certification-for-us-east-ohio-and-europe-paris-regions/

Amazon Web Services is pleased to announce that our US East (Ohio) and Europe (Paris) Regions have been re-certified through October 2023 by the GSM Association (GSMA) under its Security Accreditation Scheme Subscription Management (SAS-SM) with scope Data Centre Operations and Management (DCOM).

The US East (Ohio) and Europe (Paris) Regions first obtained GSMA certification in September and October 2021, respectively. This renewal demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers. AWS customers who provide an embedded Universal Integrated Circuit Card (eUICC) for mobile devices can run their remote provisioning applications with confidence in the AWS Cloud in the GSMA-certified Regions.

For up-to-date information related to the certification, visit the AWS Compliance Program page and choose GSMA under Europe, Middle East & Africa.

AWS was evaluated by independent third-party auditors selected by GSMA. The Certificate of Compliance that shows that AWS achieved GSMA compliance status is available on the GSMA website and through AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page. If you have feedback about this post, you can submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

Author

Janice Leung

Janice is a security audit program manager at AWS, based in New York. She leads security audits across Europe and has previously worked in security assurance and technology risk management in the financial industry for 10 years.

Making peering easy with the new Cloudflare Peering Portal

Post Syndicated from David Tuber original https://blog.cloudflare.com/making-peering-easy-with-the-new-cloudflare-peering-portal/

Making peering easy with the new Cloudflare Peering Portal

Making peering easy with the new Cloudflare Peering Portal

In 2018, we launched the Cloudflare Peering Portal, which allows network operators to see where your traffic is coming from and to identify the best possible places to interconnect with Cloudflare. We’re excited to announce that we’ve made it even easier to interconnect with Cloudflare through this portal by removing Cloudflare-specific logins and allowing users to request sessions in the portal itself!

We’re going to walk through the changes we’ve made to make peering easier, but before we do that, let’s talk a little about peering: what it is, why it’s important, and how Cloudflare is making peering easier.

What is peering and why is it important?

Put succinctly, peering is the act of connecting two networks together. If networks are like towns, peering is the bridges, highways, and streets that connect the networks together. There are lots of different ways to connect networks together, but when networks connect, traffic between them flows to their destination faster. The reason for this is that peering reduces the number of Border Gateway Protocol (BGP) hops between networks.

What is BGP?

For a quick refresher, Border Gateway Protocol (or BGP for short) is a protocol that propagates instructions on how networks should forward packets so that traffic can get from its origin to its destination. BGP provides packets instructions on how to get from one network to another by indicating which networks the packets need to go through to get to the destination, prioritizing the paths with the smallest number of hops between origin and destination. BGP sees networks as Autonomous Systems (AS), and each AS has its own number. For example, Cloudflare’s ASN is 13335.

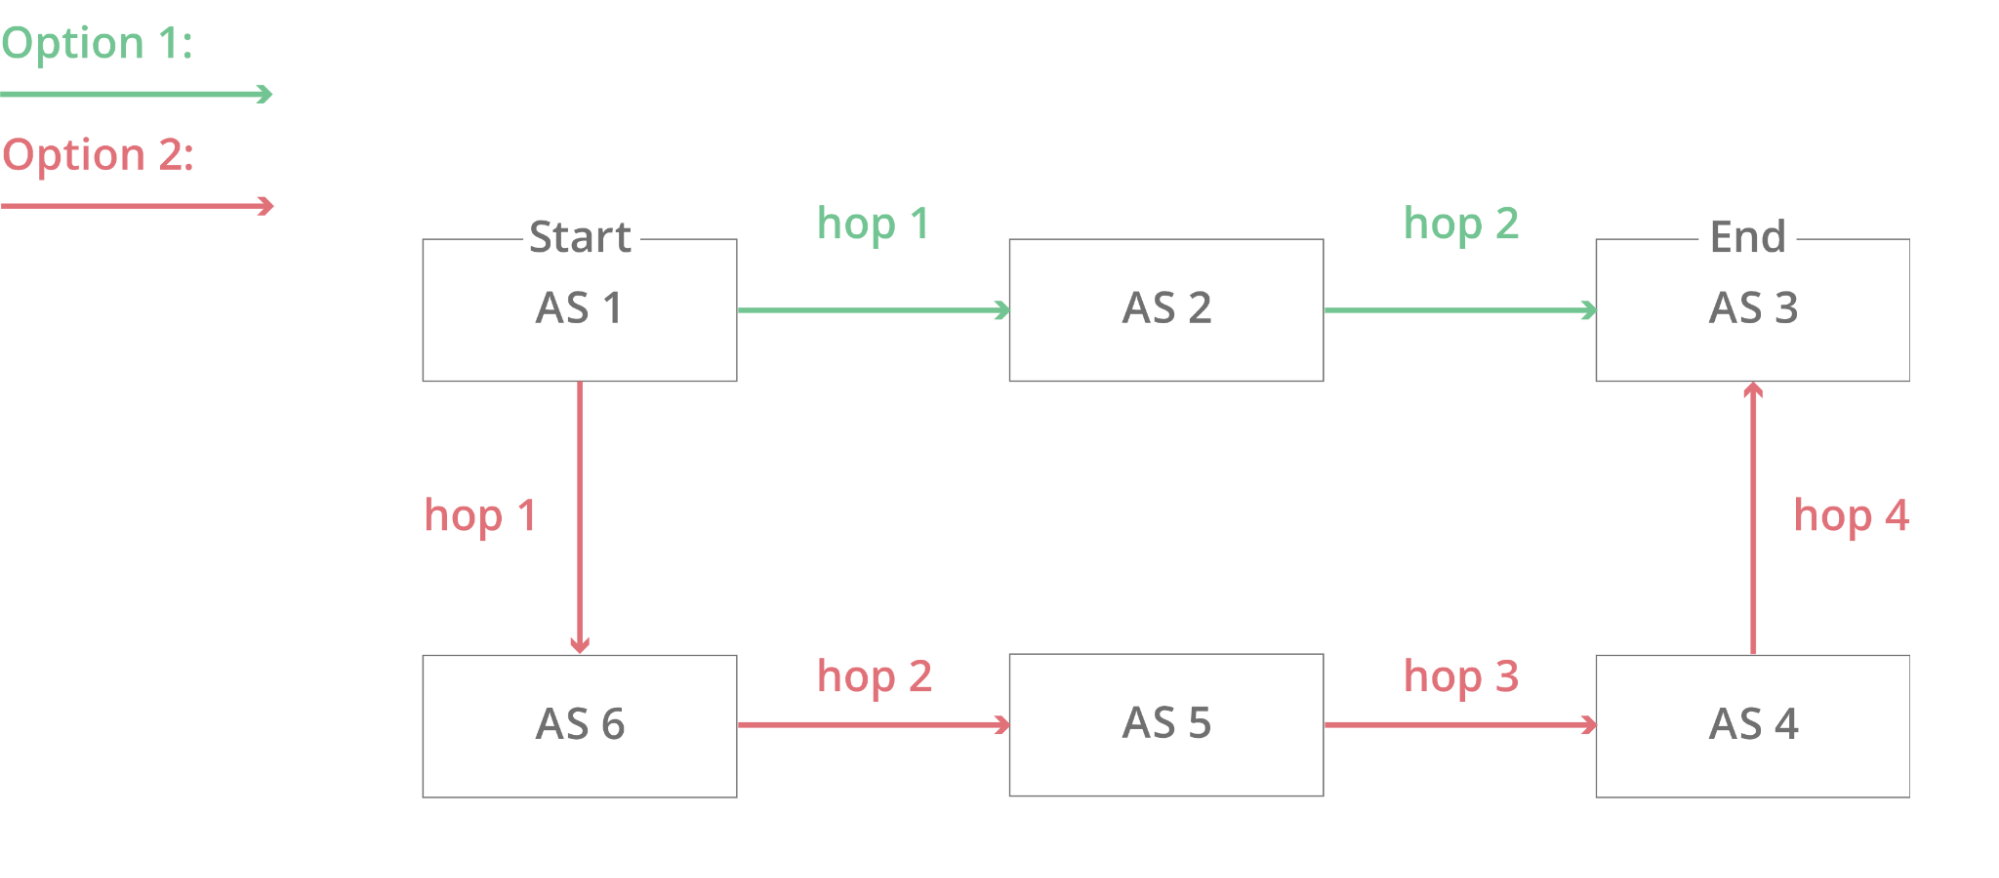
In the example below, AS 1 is trying to send packets to AS 3, but there are two possible paths the packets can go:

Making peering easy with the new Cloudflare Peering Portal

The BGP decision algorithm will select the path with the least number of hops, meaning that the path the packets will take is AS 1 → AS 2 → AS 3.

When two networks peer with each other, the number of networks needed to connect AS 1 and AS 3 is reduced to one, because AS 1 and AS 3 are directly connected with each other. But “connecting with” another network can be kind of vague, so let’s be more specific. In general, there are three ways that networks can connect with other networks: directly through Private Network Interconnects (PNI), at Internet Exchanges (IX), and through transit networks that connect with many networks.

Private Network Interconnect

A private network interconnect (PNI) sounds complicated, but it’s really simple at its core: it’s a cable connecting two networks to each other. If networks are in the same datacenter facility, it’s often easy for these two networks to connect and by doing so over a private connection, they can get dedicated bandwidth to each other as well as reliable uptime. Cloudflare has a product called Cloudflare Network Interconnect (CNI) that allows other networks to directly connect their networks to Cloudflare in this way.

Internet Exchanges

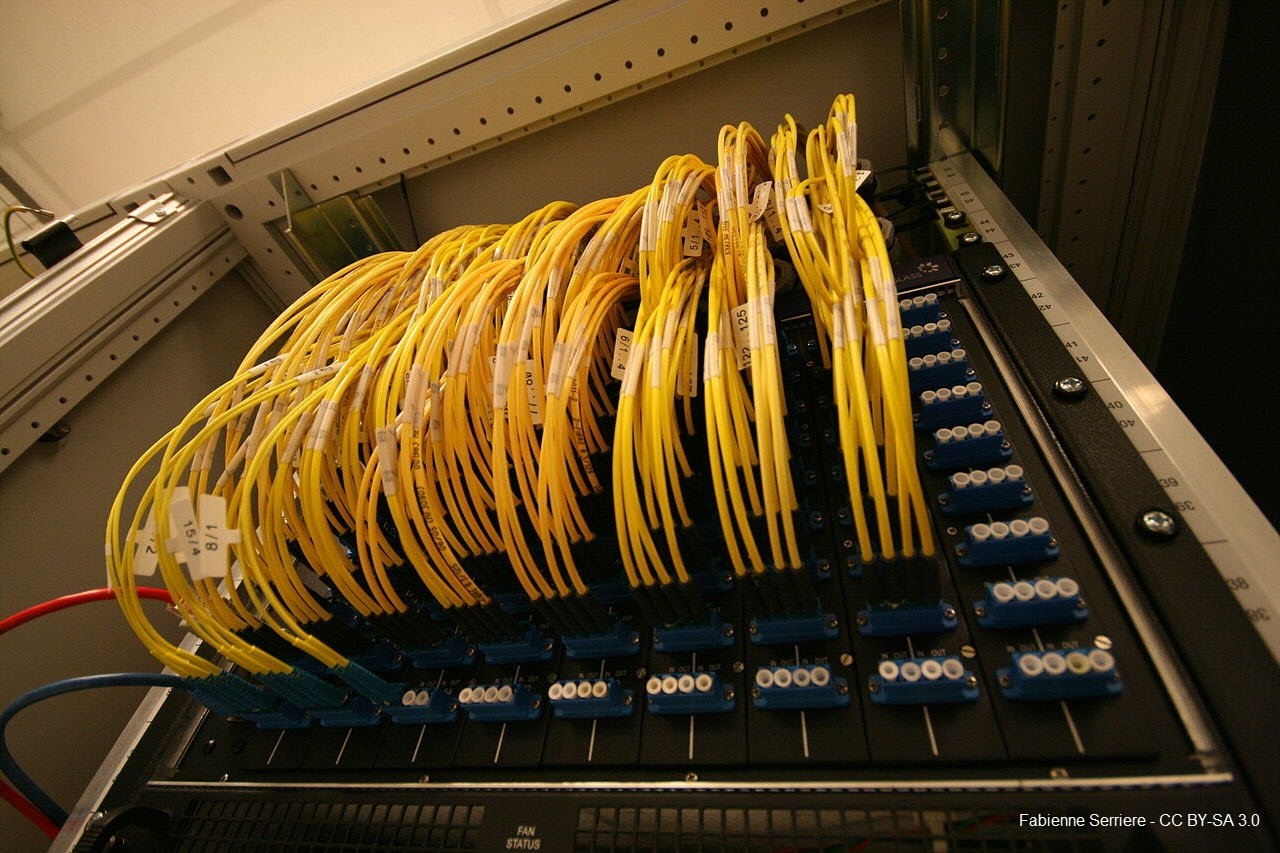
An Internet exchange (IX) is a building that specifically houses many networks in the same place. Each network gets one or more ports, and plugs into what is essentially a shared switch so that every network has the potential to interconnect. These switches are massive and house hundreds, even thousands of networks. This is similar to a PNI, but instead of two networks directly connecting to each other, thousands of networks connect to the same device and establish BGP sessions through that device.

Making peering easy with the new Cloudflare Peering Portal
Fabienne Serriere: An optical patch panel of the AMS-IX Internet exchange point, in Amsterdam, Netherlands. CC BY-SA 3.0

At Internet Exchanges, traffic is generally exchanged between networks free of charge, and it’s a great way to interconnect a network with other networks and save money on bandwidth between networks.

Transit networks

Transit networks are networks that are specifically designed to carry packets between other networks. These networks peer at Internet Exchanges and directly with many other networks to provide connectivity for your network without having to get PNIs or IX presence with networks. This service comes at a price, and may impact network performance as the transit network is an intermediary hop between your network and the place your traffic is trying to reach. Transit networks aren’t peering, but they do peering on your behalf.

No matter how you may decide to connect your network to Cloudflare, we have an open peering policy, and strongly encourage you to connect your networks directly to Cloudflare. If you’re interested, you can get started by going through the Cloudflare Peering Portal, which has now been made even easier. But let’s take a second to talk about why peering is so important.

Why is peering important?

Peering is important on the Internet for three reasons: it distributes traffic across many networks reducing single points of failure of the Internet, it often reduces bandwidth prices on the Internet making overall costs lower, and it improves performance by removing network hops. Let’s talk about each of those benefits.

Peering improves the overall uptime of the Internet by distributing traffic across multiple networks, meaning that if one network goes down, traffic from your network will still be able to reach your users. Compare that to connecting to a transit network: if the transit network has an issue, your network will be unreachable because that network was the only thing connecting your network to the rest of the Internet (unless you decide to pay multiple transit providers). With peering, any individual network failure will not completely impact the ability for your users to reach your network.

Peering helps reduce your network bandwidth costs because it distributes the cost you pay an Internet Exchange for a port across all the networks you interconnect with at the IX. If you’re paying \$1000/month for a port at an IX, and you’re peered with 100 networks there, you’re effectively paying \$10/network, as opposed to paying \$1000/month to connect to one transit network. Furthermore, many networks including Cloudflare have open peering policies and settlement free peering, which means we don’t charge you to send traffic to us or the other way round, making peering even more economical.

Peering also improves performance for Internet traffic by bringing networks closer together, reducing the time it takes for a packet to go from one network to another. The more two networks peer with each other, the more physical places on the planet they can exchange traffic directly, meaning that users everywhere see better performance.

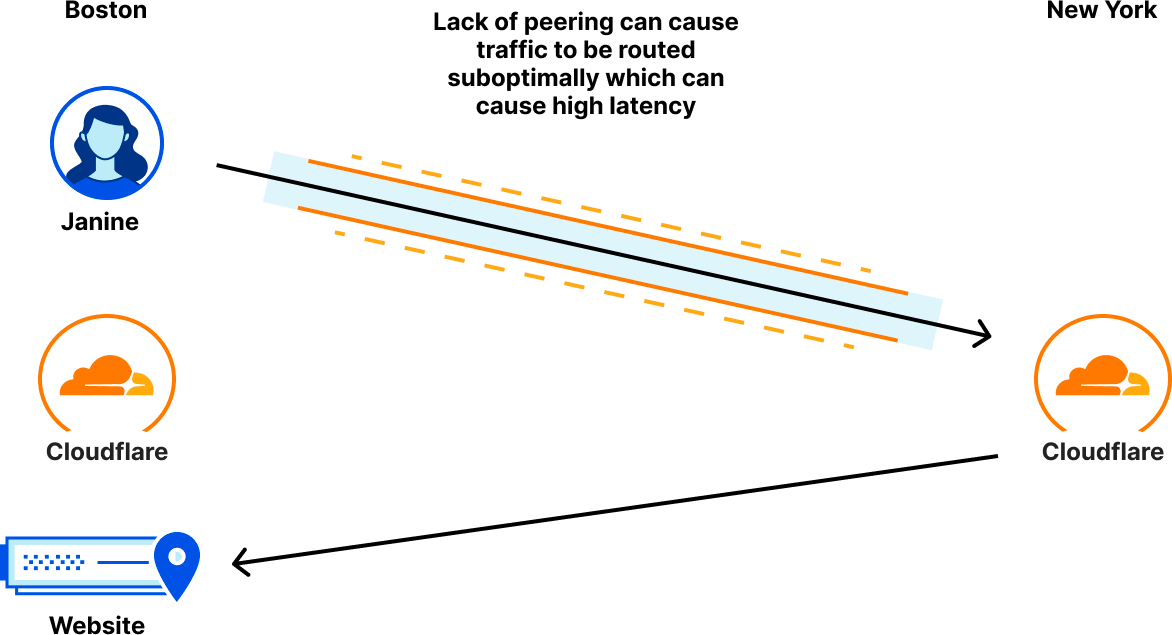
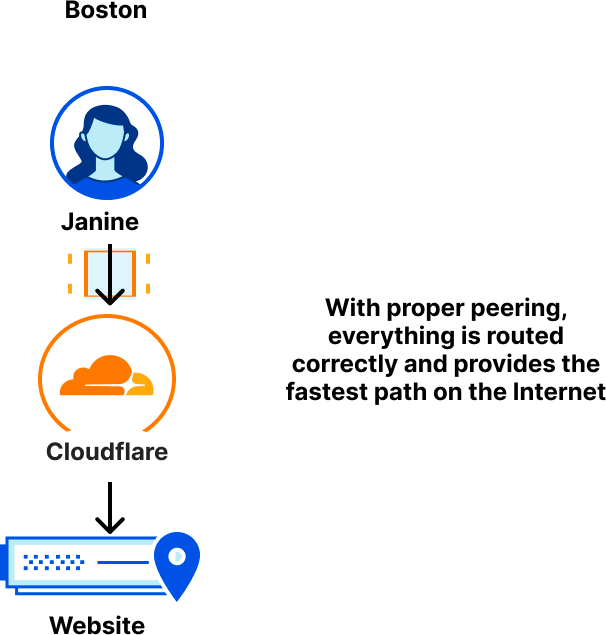
Here’s an example. Janine is trying to order food from Acme Food Services, a site protected by Cloudflare. She lives in Boston and connects to Cloudflare via her ISP. Acme Food Services has their origin in Boston as well, so for Janine to see the fastest performance, her ISP should connect to Cloudflare in Boston and then Cloudflare should route her traffic directly to the Acme origin in Boston. Unfortunately for Janine, her ISP doesn’t peer with Cloudflare in Boston, but instead peers with Cloudflare in New York: meaning that when Janine connects to Acme, her traffic is going through her ISP to New York before it reaches Cloudflare, and then all the way back to Boston to the Acme origins!

Making peering easy with the new Cloudflare Peering Portal

But with proper peering, we can ensure that traffic is routed over the fastest possible path to ensure Janine connects to Cloudflare in Boston and everything stays local:

Making peering easy with the new Cloudflare Peering Portal

Fortunately for Janine, Cloudflare peers with over 10,000 networks in the world in over 275 locations, so high latency on the network is rare. And every time a new network peers with us, we help make user traffic even faster. So now let’s talk about how we’ve made peering even easier.

Cloudflare Peering Portal supports PeeringDB login

Cloudflare, along with many other networks, rely on PeeringDB as a source of truth for which networks are present on the Internet. PeeringDB is a community-maintained database of all the networks that are present on the Internet and what datacenter facilities and IXs they are present at, as well as what IPs are used for peering at each public location. Many networks, including Cloudflare, require you to have an account on PeeringDB before you can initiate a peering session with their network.

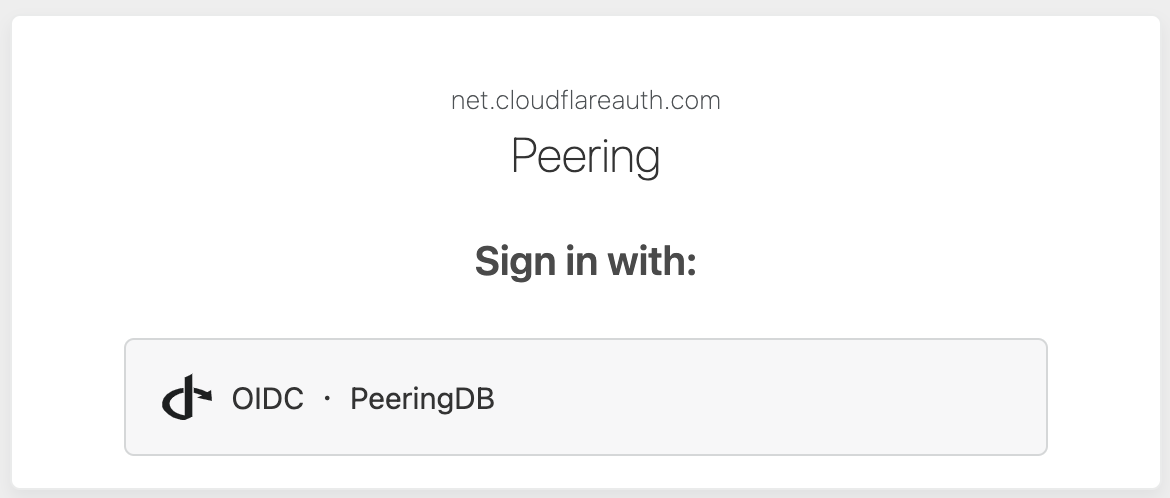
You can now use that same PeeringDB account to log into the Cloudflare Peering Portal directly, saving you the need to make a specific Cloudflare Peering Portal account.

When you log into the Cloudflare Peering Portal, simply click on the PeeringDB login button and enter your PeeringDB credentials. Cloudflare will then use this login information to determine what networks you are responsible for and automatically load data for those networks.

Making peering easy with the new Cloudflare Peering Portal

From here you can see all the places your network exchanges traffic with Cloudflare. You can see all the places you currently have direct peering with us, as well as locations for potential peering: places you could peer with us but currently don’t. Wouldn’t it be great if you could just click a button and configure a peering session with Cloudflare directly from that view? Well now you can!

Requesting sessions in the Peering Portal

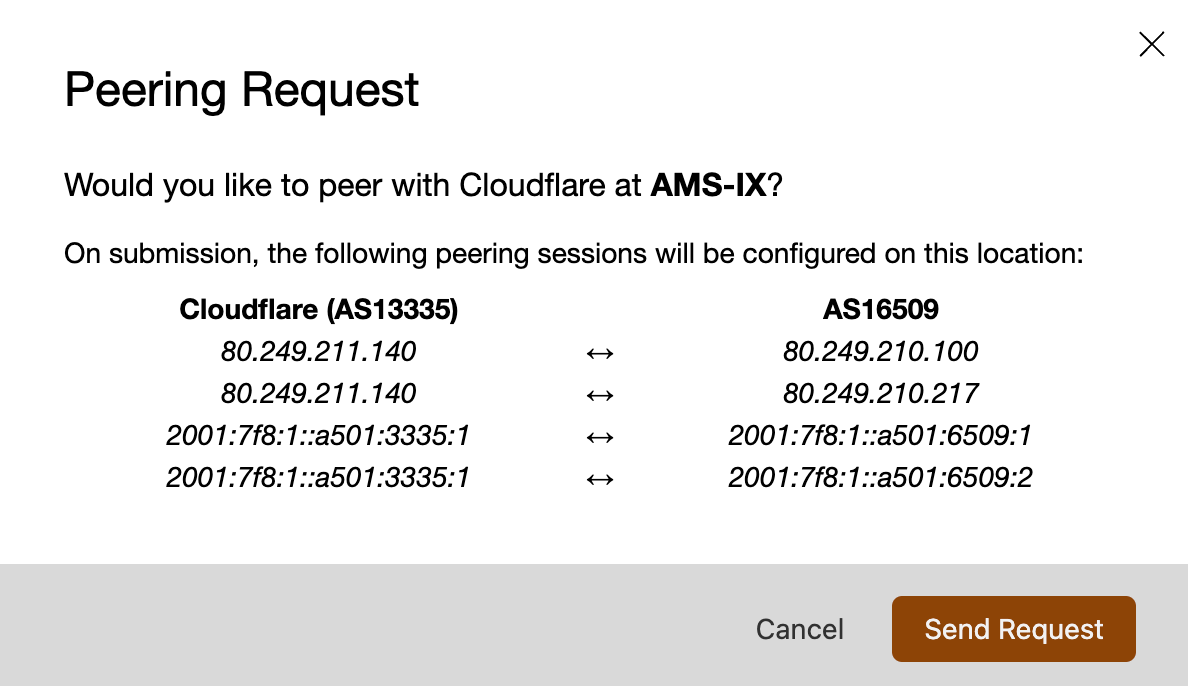
Starting today, you can now request peering sessions with Cloudflare at Internet Exchanges right from the peering portal, making it even easier to get connected with Cloudflare. When you’re looking at potential peering sessions in the portal, you’ll now see a button that will allow you to verify your peering information is correct, and if it is to proceed with a peering request:

Making peering easy with the new Cloudflare Peering Portal

Once you click that button, a ticket will go immediately to our network team to configure a peering session with you using the details already provided in PeeringDB. Our network team looks at whether we already have existing connections with your network at that location, and also what the impact to your Internet traffic will be if we peer with you there. Once we’ve evaluated these variables, we’ll proceed to establish a BGP session with you at the location and inform you via email that you’ve already provided via PeeringDB. Then all you have to do is accept the BGP sessions, and you’ll be exchanging traffic with Cloudflare!

Peer with Cloudflare today!

It has never been easier to peer with Cloudflare, and our simplified peering portal will make it even easier to get connected. Visit our peering portal today and get started on the path of faster, cheaper connectivity to Cloudflare!

Automate Amazon Redshift Serverless data warehouse management using AWS CloudFormation and the AWS CLI

Post Syndicated from Ranjan Burman original https://aws.amazon.com/blogs/big-data/automate-amazon-redshift-serverless-data-warehouse-management-using-aws-cloudformation-and-the-aws-cli/

Amazon Redshift Serverless makes it simple to run and scale analytics without having to manage the instance type, instance size, lifecycle management, pausing, resuming, and so on. It automatically provisions and intelligently scales data warehouse compute capacity to deliver fast performance for even the most demanding and unpredictable workloads, and you pay only for what you use. Just load your data and start querying right away in the Amazon Redshift Query Editor or in your favorite business intelligence (BI) tool and continue to enjoy the best price performance and familiar SQL features in an easy-to-use, zero administration environment.

Redshift Serverless separates compute and storage and introduces two abstractions:

  • Workgroup – A workgroup is a collection of compute resources. It groups together compute resources like RPUs, VPC subnet groups, and security groups.
  • Namespace – A namespace is a collection of database objects and users. It groups together data objects, such as databases, schemas, tables, users, or AWS Key Management Service (AWS KMS) keys for encrypting data.

Some organizations want to automate the creation of workgroups and namespaces for automated infrastructure management and consistent configuration across environments, and provide end-to-end self-service capabilities. You can automate the workgroup and namespace management operations using the Redshift Serverless API, the AWS Command Line Interface (AWS CLI), or AWS CloudFormation, which we demonstrate in this post.

Solution overview

In the following sections, we discuss the automation approaches for various tasks involved in Redshift Serverless data warehouse management using AWS CloudFormation (for more information, see RedshiftServerless resource type reference) and the AWS CLI (see redshift-serverless).

The following are some of the key use cases and appropriate automation approaches to use with AWS CloudFormation:

  • Enable end-to-end self-service from infrastructure setup to querying
  • Automate data consumer onboarding for data provisioned through AWS Data Exchange
  • Accelerate workload isolation by creating endpoints
  • Create a new data warehouse with consistent configuration across environments

The following are some of the main use cases and approaches for the AWS CLI:

  • Automate maintenance operations:
    • Backup and limits
    • Modify RPU configurations
    • Manage limits
  • Automate migration from provisioned to serverless

Prerequisites

To run the operations described in this post, make sure that this user or role has AWS Identity Access and Management (IAM) arn:aws:iam::aws:policy/AWSCloudFormationFullAccess, and either the administrator permission arn:aws:iam::aws:policy/AdministratorAccess or the full Amazon Redshift permission arn:aws:iam::aws:policy/AmazonRedshiftFullAccess policy attached. Refer to Security and connections in Amazon Redshift Serverless for further details.

You should have at least three subnets, and they must span across three Availability Zones.It is not enough if just 3 subnets created in same availability zone. To create a new VPC and subnets, use the following CloudFormation template to deploy in your AWS account.

Create a Redshift Serverless namespace and workgroup using AWS CloudFormation

AWS CloudFormation helps you model and set up your AWS resources so that you can spend less time on infrastructure setup and more time focusing on your applications that run in AWS. You create a template that describes all the AWS resources that you want, and AWS CloudFormation takes care of provisioning and configuring those resources based on the given input parameters.

To create the namespace and workgroup for a Redshift Serverless data warehouse using AWS CloudFormation, complete the following steps:

  1. Choose Launch Stack to launch AWS CloudFormation in your AWS account with a template:
  2. For Stack name, enter a meaningful name for the stack, for example, rsserverless.
  3. Enter the parameters detailed in the following table.
Parameters Default Allowed Values Description
Namespace . N/A The name of the namespace of your choice to be created.
Database Name dev N/A The name of the first database in the Redshift Serverless environment.
Admin User Name admin N/A The administrator’s user name for the Redshift Serverless namespace being create.
Admin User Password . N/A The password associated with the admin user.
Associate IAM Role . Comma-delimited list of ARNs of IAM roles Associate an IAM role to your Redshift Serverless namespace (optional).
Log Export List userlog, connectionlog, useractivitylog userlog, connectionlog, useractivitylog Provide comma-separated values from the list. For example, userlog, connectionlog, useractivitylog. If left blank, LogExport is turned off.
Workgroup . N/A The workgroup name of your choice to be created.
Base RPU 128 Minimum value of 32 and maximum value of 512 The base RPU for the Redshift Serverless workgroup.
Publicly accessible false true, false Indicates if the Redshift Serverless instance is publicly accessible.
Subnet Ids . N/A You must have at least three subnets, and they must span across three Availability Zones.
Security Group Id . N/A The list of security group IDs in your VPC.
Enhanced VPC Routing false true, false The value that specifies whether to enable enhanced VPC routing, which forces Redshift Serverless to route traffic through your VPC.
  1. Pass the parameters provided to the AWS::RedshiftServerless::Namespace and AWS::RedshiftServerless::Workgroup resource types:
    Resources:
      RedshiftServerlessNamespace:
        Type: 'AWS::RedshiftServerless::Namespace'
        Properties:
          AdminUsername:
            Ref: AdminUsername
          AdminUserPassword:
            Ref: AdminUserPassword
          DbName:
            Ref: DatabaseName
          NamespaceName:
            Ref: NamespaceName
          IamRoles:
            Ref: IAMRole
          LogExports:
            Ref: LogExportsList        
      RedshiftServerlessWorkgroup:
        Type: 'AWS::RedshiftServerless::Workgroup'
        Properties:
          WorkgroupName:
            Ref: WorkgroupName
          NamespaceName:
            Ref: NamespaceName
          BaseCapacity:
            Ref: BaseRPU
          PubliclyAccessible:
            Ref: PubliclyAccessible
          SubnetIds:
            Ref: SubnetId
          SecurityGroupIds:
            Ref: SecurityGroupIds
          EnhancedVpcRouting:
            Ref: EnhancedVpcRouting        
        DependsOn:
          - RedshiftServerlessNamespace

Perform namespace and workgroup management operations using the AWS CLI

The AWS CLI is a unified tool to manage your AWS services. With just one tool to download and configure, you can control multiple AWS services from the command line and automate them through scripts.

To run the Redshift Serverless CLI commands, you need to install the latest version of AWS CLI. For instructions, refer to Installing or updating the latest version of the AWS CLI.

Now you’re ready to complete the following steps:

Use the following command to create a new namespace:

aws redshift-serverless create-namespace \
    --admin-user-password '<password>' \
    --admin-username cfn-blog-admin \
    --db-name cfn-blog-db \
    --namespace-name 'cfn-blog-ns'

The following screenshot shows an example output.

create-namespace

Use the following command to create a new workgroup mapped to the namespace you just created:

aws redshift-serverless create-workgroup \
    --base-capacity 128 \
    --namespace-name 'cfn-blog-ns' \
    --no-publicly-accessible \
    --security-group-ids "sg-0269bd680e0911ce7" \
    --subnet-ids "subnet-078eedbdd99398568" "subnet-05defe25a59c0e4c2" "subnet-0f378d07e02da3e48"\
    --workgroup-name 'cfn-blog-wg'

The following is an example output.

create workgroup

To allow instances and devices outside the VPC to connect to the workgroup, use the publicly-accessible option in the create-workgroup CLI command.

To verify the workgroup has been created and is in AVAILABLE status, use the following command:

aws redshift-serverless get-workgroup \
--workgroup-name 'cfn-blog-wg' \
--output text \
--query 'workgroup.status'

The following screenshot shows our output.

Regardless of whether your snapshot was made from a provisioned cluster or serverless workgroup, it can be restored into a new serverless workgroup. Restoring a snapshot replaces the namespace and workgroup with the contents of the snapshot.

Use the following command to restore from a snapshot:

aws redshift-serverless restore-from-snapshot \
--namespace-name 'cfn-blog-ns' \
--snapshot-arn arn:aws:redshift:us-east-1:<account-id>:snapshot:<cluster-identifier>/<snapshot-identifier> \
--workgroup-name 'cfn-blog-wg'

The following is an example output.

To check the workgroup status, run the following command:

aws redshift-serverless get-workgroup \
--workgroup-name 'cfn-blog-wg' \
--output text \
--query 'workgroup.status'

To create a snapshot from an existing namespace, run the following command:

aws redshift-serverless create-snapshot \
--namespace-name cfn-blog-ns \
--snapshot-name cfn-blog-snapshot-from-ns \
--retention-period 7

The following is an example output.

Redshift Serverless creates recovery points of your namespace that are available for 24 hours. To keep your recovery point longer than 24 hours, convert it to a snapshot.

To find the recovery points associated to your namespace, run the following command:

aws redshift-serverless list-recovery-points \
--namespace-name cfn-blog-ns \
--no-paginate

The following an example output with the list of all the recovery points.

list recovery points

Let’s take the latest recoveryPointId from the list and convert to snapshot.

To create a snapshot from a recovery point, run the following command:

aws redshift-serverless convert-recovery-point-to-snapshot \
--recovery-point-id f9eaf9ac-a98d-4809-9eee-869ef03e98b4 \
--retention-period 7 \
--snapshot-name cfn-blog-snapshot-from-rp

The following is an example output.

convert-recovery-point

In addition to restoring a snapshot to a serverless namespace, you can also restore from a recovery point.

  1. First, you need to find the recovery point identifier using the list-recovery-points command.
  2. Then use the following command to restore from a recovery point:
aws redshift-serverless restore-from-recovery-point \
--namespace-name cfn-blog-ns \
--recovery-point-id 15c55fb4-d973-4d8a-a8fe-4741e7911137 \
--workgroup-name cfn-blog-wg

The following is an example output.

restore from recovery point

The base RPU determines the starting capacity for your serverless environment.

Use the following command to modify the base RPU based on your workload requirements:

aws redshift-serverless update-workgroup \
--base-capacity 256 \
--workgroup-name 'cfn-blog-wg'

The following is an example output.

Run the following command to verify the workgroup base RPU capacity has been modified to 256:

aws redshift-serverless get-workgroup \
--workgroup-name 'cfn-blog-wg' \
--output text \
--query 'workgroup.baseCapacity'


To keep costs predictable for Redshift Serverless, you can set the maximum RPU hours used per day, per week, or per month. In addition, you can take action when the limit is reached. Actions include: write a log entry to a system table, receive an alert, or turn off user queries.

Use the following command to first get the workgroup ARN:

aws redshift-serverless get-workgroup --workgroup-name 'cfn-blog-wg' \
--output text \
--query 'workgroup.workgroupArn'

The following screenshot shows our output.

Use the workgroupArn output from the preceding command with the following command to set the daily RPU usage limit and set the action behavior to log:

aws redshift-serverless create-usage-limit \
--amount 256 \
--breach-action log \
--period daily \
--resource-arn arn:aws:redshift-serverless:us-east-1:<aws-account-id>:workgroup/1dcdd402-8aeb-432e-8833-b1f78a112a93 \
--usage-type serverless-compute

The following is an example output.

Conclusion

You have now learned how to automate management operations on Redshift Serverless namespaces and workgroups using AWS CloudFormation and the AWS CLI. To automate creation and management of Amazon Redshift provisioned clusters, refer to Automate Amazon Redshift Cluster management operations using AWS CloudFormation.


About the Authors

Ranjan Burman is a Analytics Specialist Solutions Architect at AWS. He specializes in Amazon Redshift and helps customers build scalable analytical solutions. He has more than 15 years of experience in different database and data warehousing technologies. He is passionate about automating and solving customer problems with the use of cloud solutions.

Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 16 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Urvish Shah is a Senior Database Engineer at Amazon Redshift. He has more than a decade of experience working on databases, data warehousing and in analytics space. Outside of work, he enjoys cooking, travelling and spending time with his daughter.

Ingest VPC flow logs into Splunk using Amazon Kinesis Data Firehose

Post Syndicated from Ranjit Kalidasan original https://aws.amazon.com/blogs/big-data/ingest-vpc-flow-logs-into-splunk-using-amazon-kinesis-data-firehose/

In September 2017, during the annual Splunk.conf, Splunk and AWS jointly announced Amazon Kinesis Data Firehose integration to support Splunk Enterprise and Splunk Cloud as a delivery destination. This native integration between Splunk Enterprise, Splunk Cloud, and Kinesis Data Firehose is designed to make AWS data ingestion setup seamless, while offering a secure and fault-tolerant delivery mechanism. We want to enable you to monitor and analyze machine data from any source and use it to deliver operational intelligence and optimize IT, security, and business performance.

With Kinesis Data Firehose, you can use a fully managed, reliable, and scalable data streaming solution to Splunk. In September 2022, AWS announced a new Amazon Virtual Private Cloud (Amazon VPC) feature that enables you to create VPC flow logs to send the flow log data directly into Kinesis Data Firehose as a destination. Previously, you could send VPC flow logs to either Amazon CloudWatch Logs or Amazon Simple Storage Service (Amazon S3) before it was ingested by other AWS or Partner tools. In this post, we show you how to use this feature to set up VPC flow logs for ingesting into Splunk using Kinesis Data Firehose.

Overview of solution

We deploy the following architecture to ingest data into Splunk.

We create a VPC flow log in an existing VPC to send the flow log data to a Kinesis Data Firehose delivery stream. This delivery stream has an AWS Lambda function enabled for data transformation and has destination settings to point to the Splunk endpoint along with an HTTP Event Collector (HEC) token.

Prerequisites

Before you begin, ensure that you have the following prerequisites:

  • AWS account – If you don’t have an AWS account, you can create one. For more information, see Setting Up for Amazon Kinesis Data Firehose.
  • Splunk AWS Add-on – Ensure you install the Splunk AWS Add-on app from Splunkbase in your Splunk deployment. This app provides the required source types and event types mapping to AWS machine data.
  • HEC token – In your Splunk deployment, set up an HEC token with the source type aws:cloudwatchlogs:vpcflow.

Create the transformation Lambda function

Integrating VPC flow logs with Kinesis Data Firehose requires a Lambda function to transform the flow log records. The data that VPC flow logs sends to the delivery stream is encoded as JSON records. However, Splunk expects this as raw flow log data. Therefore, when you create the delivery stream, you enable data transformation and configure a Lambda function to transform the flow log data to raw format. Kinesis Data Firehose then sends the data in raw format to Splunk.

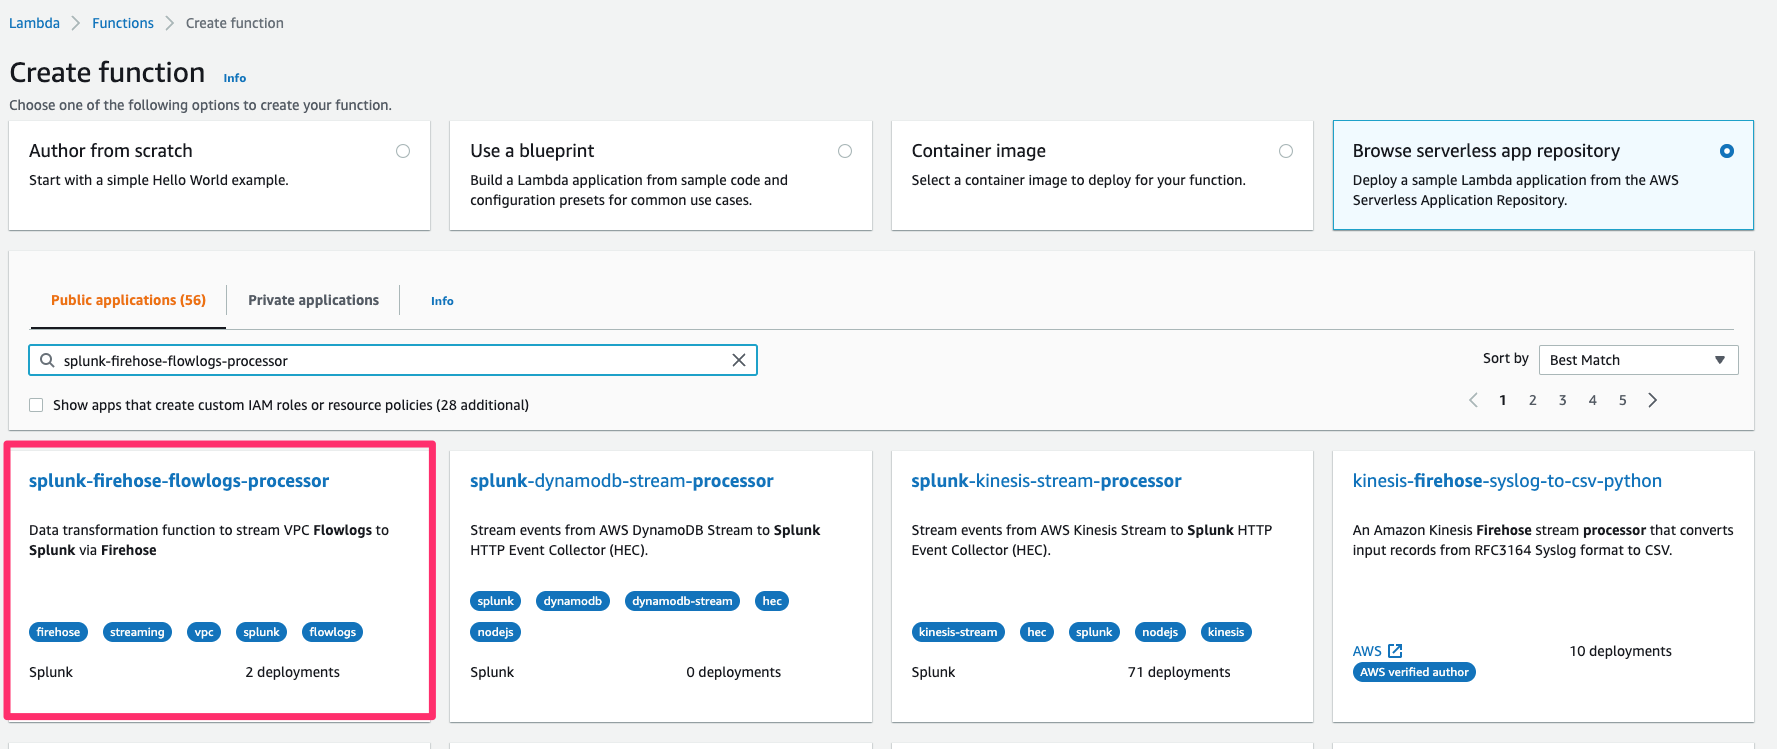
You can deploy this transformation Lambda function as a serverless application from the Lambda serverless app repository on the Lambda console. The name of this application is splunk-firehose-flowlogs-processor.

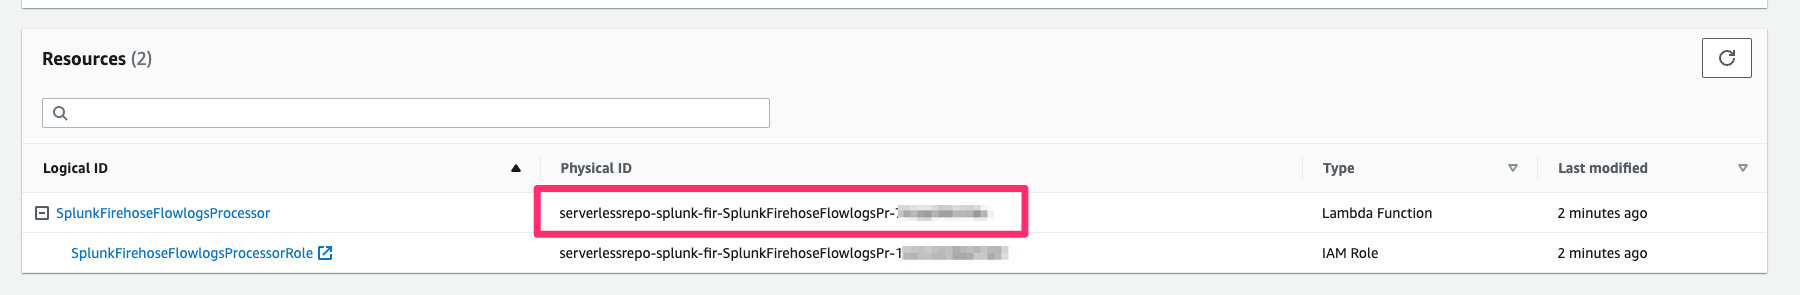
After it’s deployed, you can see a Lambda function and an AWS Identity and Access Management (IAM) role getting deployed on the console. Note the physical ID of the Lambda function; you use this when you create the Firehose delivery stream in the next step.

Create a Kinesis Data Firehose delivery stream

In this step, you create a Kinesis Data Firehose delivery stream to receive the VPC flow log data and deliver that data to Splunk.

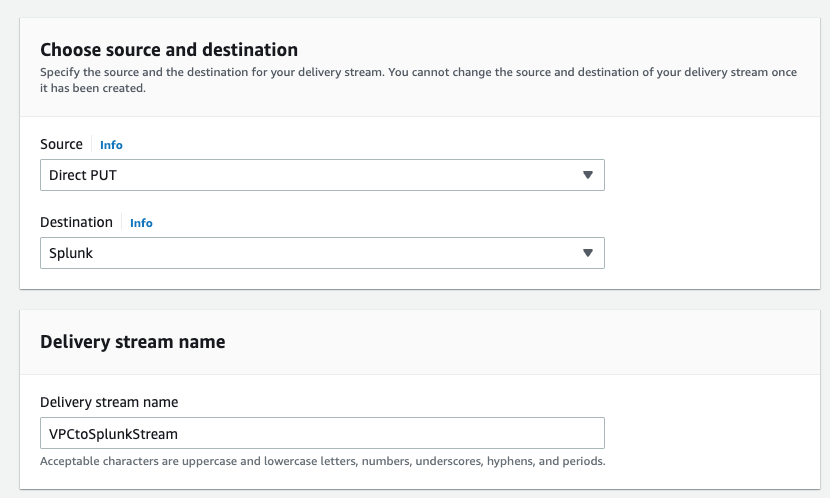
  1. On the Kinesis Data Firehose console, create a new delivery stream.
  2. For Source, choose Direct PUT.
  3. For Destination, choose Splunk.
  4. For Delivery stream name, enter a name (for example, VPCtoSplunkStream).
  5. In the Transform records section, for Data transformation, select Enabled.
  6. For AWS Lambda function, choose Browse.
  7. Select the function you created earlier by looking for the physical ID.
  8. Choose Choose.
  9. In the Destination settings section, for Splunk cluster endpoint, enter your endpoint.If you’re using a Splunk Cloud endpoint, refer to Configure Amazon Kinesis Firehose to send data to the Splunk platform for different Splunk cluster endpoint values.
  10. For Splunk endpoint type, select Raw endpoint.
  11. For Authentication token, enter the value of your Splunk HEC that you created as a prerequisite.
  12. In the Backup settings section, for Source record backup in Amazon S3, select Failed events only so you only save the data that fails to be ingested into Splunk.
  13. For S3 backup bucket, enter the path to an S3 bucket.
  14. Complete creating your delivery stream.

The creation process may take a few minutes to complete.

Create a VPC flow log

In this final step, you create a VPC flow log with Kinesis Data Firehose as destination type.

  1. On the Amazon VPC console, choose Your VPCs.
  2. Select the VPC for which to create the flow log.
  3. On the Actions menu, choose Create flow log.
  4. Provide the required settings for Filter:
    1. If you want to filter the flow logs, select Accept traffic or Reject traffic.
    2. Select All if you need all the information sent to Splunk.
  5. For Maximum aggregation interval, select a suitable interval for your use case.Select the minimum setting of 1 minute interval if you need the flow log data to be available for near-real-time analysis in Splunk.
  6. For Destination, select Send to Kinesis Firehose in the same account if the delivery stream is set up on the same account where you create the VPC flow logs.If you want to send the data to a different account, refer to Publish flow logs to Kinesis Data Firehose.
  7. For Log record format, if you leave it at AWS default format, the flow logs are sent as version 2 format. Alternatively, you can specify which fields you need to be captured and sent to Splunk.For more information on log format and available fields, refer to Flow log records.
  8. Review all the parameters and create the flow log.Within a few minutes, you should be able to see the data in Splunk.
  9. Open your Splunk console and navigate to the Search tab of the Search & Reporting app.
  10. Run the following SPL query to look at sample VPC flow log records:
    index=<index name> sourcetype="aws:cloudwatchlogs:vpcflow"

Clean up

To avoid incurring future charges, delete the resources you created in the following order:

  1. Delete the VPC flow log.
  2. Delete the Kinesis Data Firehose delivery stream.
  3. Delete the serverless application to delete the transformation Lambda function.
  4. If you created a new VPC and new resources in the VPC, then delete the resources and VPC.

Conclusion

You can use VPC flow log data in multiple Splunk solutions, like the Splunk App for AWS Security Dashboards for traffic analysis or Splunk Security Essentials, which uses the data to provide deeper insights into the security posture of your AWS environment. Using Kinesis Data Firehose to send VPC flow log data into Splunk provides many benefits. This managed service can automatically scale to meet the data demand and provide near-real-time data analysis. Try out this new quick and hassle-free way of sending your VPC flow logs to Splunk Enterprise or Splunk Cloud Platform using Kinesis Data Firehose.

You can deploy this solution today on your AWS account by following the Kinesis Data Firehose Immersion Day Lab for Splunk


About the authors

Ranjit Kalidasan is a Senior Solutions Architect with Amazon Web Services based in Boston, Massachusetts. He is Partner Solutions Architect helping security ISV partners to co-build and co-market solutions with AWS. He brings over 20 years of experience in Information technology helping global customers implement complex solutions for Security & Analytics. You can connect with Ranjit in Linkedin.

[$] The search for the correct amount of split-lock misery

Post Syndicated from original https://lwn.net/Articles/911219/

Unlike many other architectures, x86 systems support atomic operations that
affect more than one cache line. This support comes at a cost, though, in
terms of overall system performance and, even, security. Over the last few
years, kernel developers have worked to discourage the use of this sort of
“split-lock” operation. Now, though, one group of users is feeling
a little too discouraged, leading to a discussion of how much misery can
appropriately be inflicted upon users who use problematic but
architecturally legal operations.

[The Lost Bots] S02E05: The real magic in the Magic Quadrant

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/10/19/the-lost-bots-s02e05-the-real-magic-in-the-magic-quadrant/

[The Lost Bots] S02E05: The real magic in the Magic Quadrant

In this episode, we discuss the best use of market research reports, like Magic Quadrants and Waves. If you’re in the market for a new cybersecurity solution, do you just pick a Leader and call it a day?

“Consult the MQ only after you’ve identified two vendors that would be a perfect security solution for you,” say our hosts Jeffrey Gardner, Detection and Response Practice Advisor and Stephen Davis, Lead D&R Sales Technical Advisor. When you have two that meet or exceed the requirements? “I’ll be honest, I might not care about the MQ placement,” says Davis.

Do not under any circumstances leave before the jazz hands bit: they do gather themselves and talk about how outcomes have to run the show, first and always.

Check back with us in November for our next installment of The Lost Bots!

Additional reading:

Security updates for Wednesday

Post Syndicated from original https://lwn.net/Articles/911723/

Security updates have been issued by Debian (bcel, kernel, node-xmldom, and squid), Mageia (chromium-browser-stable, dhcp, dokuwiki, firefox, golang, python-joblib, sos, and unzip), Oracle (nodejs and nodejs:16), Red Hat (firefox, kernel, kernel-rt, nodejs, nodejs:14, and thunderbird), Scientific Linux (firefox and thunderbird), Slackware (git and mozilla), SUSE (amazon-ssm-agent, caasp-release, cri-o, patchinfo, release-notes-caasp, skuba, enlightenment, libreoffice, netty, nodejs12, nodejs14, nodejs16, pngcheck, postgresql-jdbc, python-waitress, rubygem-activesupport-5_1, and tcl), and Ubuntu (frr, git, libksba, and linux-azure-4.15).

Let’s Architect! Architecting with Amazon DynamoDB

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-architecting-with-amazon-dynamodb/

NoSQL databases are an essential part of the technology industry in today’s world. Why are we talking about NoSQL databases? NoSQL databases often allow developers to be in control of the structure of the data, and they are a good fit for big data scenarios and offer fast performance.

In this issue of Let’s Architect!, we explore Amazon DynamoDB capabilities and potential solutions to apply in your architectures. A key strength of DynamoDB is the capability of operating at scale globally; for instance, multiple products built by Amazon are powered by DynamoDB. During Prime Day 2022, the service also maintained high availability while delivering single-digit millisecond responses, peaking at 105.2 million requests-per-second. Let’s start!

Data modeling with DynamoDB

Working with a new database technology means understanding exactly how it works and the best design practices for taking full advantage of its features.

In this video, the key principles for modeling DynamoDB tables are discussed, plus practical patterns to use while defining your data models are explored and how data modeling for NoSQL databases (like DynamoDB) is different from modeling for traditional relational databases.

With this video, you can learn about the main components of DynamoDB, some design considerations that led to its creation, and all the best practices for efficiently using primary keys, secondary keys, and indexes. Peruse the original paper to learn more about DyanamoDB in Dynamo: Amazon’s Highly Available Key-value Store.

Amazon DynamoDB uses partitioning to provide horizontal scalability

Amazon DynamoDB uses partitioning to provide horizontal scalability

Single-table vs. multi-table in Amazon DynamoDB

When considering single-table versus multi-table in DynamoDB, it is all about your application’s needs. It is possible to avoid naïve lifting-and-shifting your relational data model into DynamoDB tables. In this post, you will discover different use cases on when to use single-table compared with multi-table designs, plus understand certain data-modeling principles for DynamoDB.

Use a single-table design to provide materialized joins in Amazon DynamoDB

Use a single-table design to provide materialized joins in Amazon DynamoDB

Optimizing costs on DynamoDB tables

Infrastructure cost is an important dimension for every customer. Despite your role inside an organization, you should monitor opportunities for optimizing costs, when possible.
For this reason, we have created a guide on DynamoDB tables cost-optimization that provides several suggestions for reducing your bill at the end of the month.

Build resilient applications with Amazon DynamoDB global tables: Part 1

When you operate global systems that are spread across multiple AWS regions, dealing with data replication and writes across regions can be a challenge. DynamoDB global tables help by providing the performance of DynamoDB across multiple regions with data synchronization and multi-active database where each replica can be used for both writing and reading data.

Another use case for global tables are resilient applications with the lowest possible recovery time objective (RTO) and recovery point objective (RPO). In this blog series, we show you how to approach such a scenario.

Amazon DynamoDB active-active architecture

Amazon DynamoDB active-active architecture

See you next time!

Thanks for joining our discussion on DynamoDB. See you in a few weeks, when we explore cost optimization!

Other posts in this series

Looking for more architecture content?

AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Museum Security

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/10/museum-security.html

Interesting interview:

Banks don’t take millions of dollars and put them in plastic bags and hang them on the wall so everybody can walk right up to them. But we do basically the same thing in museums and hang the assets right out on the wall. So it’s our job, then, to either use technology or develop technology that protects the art, to hire honest guards that are trainable and able to meet the challenge and alert and so forth. And we have to keep them alert because it’s the world’s most boring job. It might be great for you to go to a museum and see it for a day, but they stand in that same gallery year after year, and so they get mental fatigue. And so we have to rotate them around and give them responsibilities that keep them stimulated and keep them fresh.

It’s a challenge. But we try to predict the items that might be most vulnerable. Which are not necessarily most valuable; some things have symbolic significance to them. And then we try to predict what the next targets might be and advise our clients that they maybe need to put special security on those items.

The collective thoughts of the interwebz