Post Syndicated from The Atlantic original https://www.youtube.com/shorts/illN98fHpvI
NVIDIA and Mediatek Ink $3.5B Investment Deal, Accelerate NVLink Fusion Adoption
Post Syndicated from Ryan Smith original https://www.servethehome.com/nvidia-and-mediatek-ink-3-5b-investment-deal-accelerate-nvlink-fusion-adoption/
NVIDIA and MediaTek have inked a new deal this week that more closely ties together the two companies financially and technologically. With NVIDIA investing $3.5B into the Taiwanese fabless chip designer, MediaTek will now offer the NVLink Fusion platform to customers designing custom XPUs at MediaTek
The post NVIDIA and Mediatek Ink $3.5B Investment Deal, Accelerate NVLink Fusion Adoption appeared first on ServeTheHome.
Leaked Russian Cyber-Operations Training Materials
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/leaked-russian-cyber-operations-training-materials.html
This is interesting:
The records describe a force-generation mechanism for several General Staff components, including the GRU, Main Operational Directorate, and 8th Directorate, which is associated with protected communications, cryptography, and information security.
[…]
The reporting also linked a 2024 Department No. 4 graduate, Aleksei Kondrashov, to Military Unit 74455, widely known as Sandworm.
That unit has been associated with destructive cyber activity against Ukraine and other targets, including the 2017 NotPetya attack.
The reports do not establish that every listed graduate participated in a named operation; assignments should therefore be described as reported unit placements, not proof of individual operational involvement.
The Bauman material reframes Russia’s cyber capability as an institutional system, not merely a collection of well-known threat groups.
It suggests that Moscow has formalized a recurring pathway from university recruitment to military service, where students receive supervised technical and ideological preparation before entering intelligence, cyber, and security roles.
For defenders, the leak reinforces the need to track Russian operations as a combined threat: espionage, destructive activity, military reconnaissance, technical surveillance, and influence campaigns may draw on related personnel pipelines and overlapping doctrine.
The exposure of Department No. 4 also provides researchers with a clearer lens for understanding how the GRU sustains cyber capacity beyond the familiar APT28 and Sandworm brand names.
Observing and evaluating production agents using OpenSearch Agent Health
Post Syndicated from Ulrich Hinze original https://aws.amazon.com/blogs/big-data/observing-and-evaluating-production-agents-using-opensearch-agent-health/
As AI agents are moving from experimental prototypes to production workloads, teams need visibility into what agents are doing and a systematic way to measure whether they’re doing it well. Traditional testing methodologies like unit and integration tests fall short for this task, as measuring an agent’s quality isn’t a straightforward true/false decision. Instead, agent observability and evaluations (evals for short) provide a two-legged solution to this problem. Agent observability captures the details of an agent’s behavior, and evals compare this behavior to the behavior that you want. With this approach, teams can monitor their agent’s quality over time and introduce agent-specific quality gates in their software development lifecycle.
In this post, we show how to combine an AI agent running on AWS with OpenSearch Agent Health for observability and evals. You will deploy an agent and its observability data pipeline to AWS, then use Agent Health as a local development tool connecting to your cloud resources.
Overview of solution
Agent observability and evaluations rely on OpenTelemetry traces to understand agent behavior. Traces describe the flow of a request through components of a system. OpenSearch Agent Health is a purpose-built tool for analyzing agent traces and running evaluations against an agent for quality control. Although Agent Health works with any open source OpenSearch installation, many AWS customers choose Amazon OpenSearch Ingestion and Amazon OpenSearch Service for ingesting and storing their OpenTelemetry data. You can connect OpenSearch Agent Health to these AWS resources to fetch live data and store its own configuration and evaluation history.
The following diagram shows the overall architecture of the solution presented in this post: 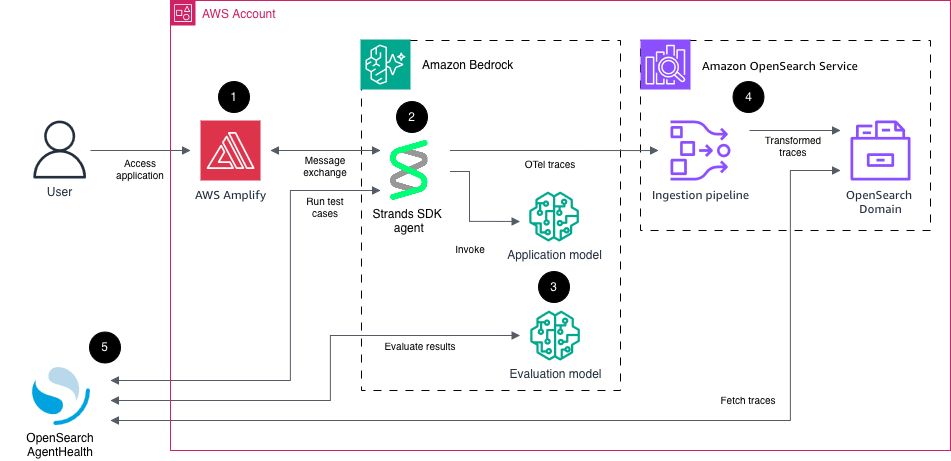
Figure 1: Solution overview
The individual parts are:
- AWS Amplify for hosting an assistant-ui chat interface. Connects to the agent backend using the Agent-User Interaction (AG-UI) protocol.
- Sample ecommerce AI agent using Strands Agents SDK, deployed to Amazon Bedrock AgentCore runtime, exposing an AG-UI Server-Sent Events (SSE) endpoint. This agent has access to multiple tools, such as product search and shopping basket operations. For this sample project, the tool calls are all simulated within the agent runtime rather than including API calls to other systems. The agent emits messages, reasoning steps, and tool calls as OpenTelemetry traces.
- Large language models (LLMs) on Amazon Bedrock. One model (Amazon Nova 2 Lite) is used to power the agent, the other model (Anthropic Claude Opus 4.6) is used to evaluate the agent behavior.
- Amazon OpenSearch Ingestion for collecting and transforming the raw agent traces and loading them into an Amazon OpenSearch Service domain. Agent traces have the same structure as regular OpenTelemetry traces, with the addition of generative AI semantics (for example, tool calls and token usage). This means a regular OpenTelemetry pipeline configuration can be used to process agent traces.
- OpenSearch Agent Health for analyzing traces and running evaluation test cases and benchmarks against the agent. Agent Health uses the same AG-UI endpoint as the front-end application. It authenticates to the application, to Amazon Bedrock for model functionality, and to Amazon OpenSearch Service using AWS SigV4 authentication.
Walkthrough
In this walkthrough, we showcase how you can use Agent Health and Strands to measure and improve your agent’s quality over time.
We follow these steps:
- Deploy solution to AWS and test the application.
- Start Agent Health locally and connect it to cloud resources.
- Explore agent traces and run evaluations.
We have created a GitHub repository for you to follow along.
Prerequisites
For this walkthrough, you should have the following prerequisites:
- An AWS account
- Git
- Node.js
- AWS Cloud Development Kit (AWS CDK)
Deploy solution to AWS and test the application
In this section, you check out the repository and deploy the infrastructure to AWS. Be aware that these steps create AWS resources that incur cost. We cover cleanup steps at the end of this post.
First, clone the repository to a local directory:
Switch to the infra folder and install dependencies:
Before you can start the deployment, determine the AWS Identity and Access Management (IAM) user or role that you will use to start Agent Health later on. In many cases, this will be the same role that you use to deploy the infrastructure. Set this ARN in your environment by issuing the following command:
Bootstrap your AWS account for use with AWS CDK:
Run the infrastructure deployment. Review and acknowledge IAM statement changes when prompted. This takes around 25 minutes to complete:
The -R parameter defines that if something fails during this deployment, the successfully provisioned resources are retained. Be aware that this command creates AWS resources, incurring cost. Review the cleanup section at the end of this post for removing all created resources.
When the deploy command finishes successfully, you should see an output like the following:
Next, create a user for your application. Retrieve the CDK output value for AgentObservabilityStack.UserPoolId. Create a user for the application using the user pool ID, an email address, and a strong password (minimum eight characters including uppercase, lowercase, letter, and digit):
You can now access the retail agent application. From the CDK output values, retrieve the value for AgentObservabilityStack.ChatUrl. Copy and paste this URL into your browser. Log in with your email and password. You should now see the agent interface:
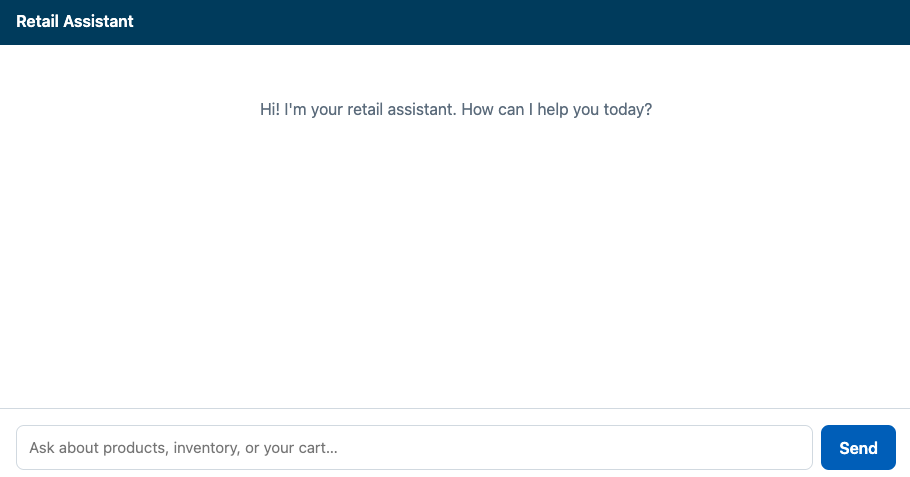
Figure 2: Sample retail agent user interface
Experiment with the application. Here is an example sequence of queries you can put in:
- Do you have books on Python?
- Is this in stock?
- Put it into my basket.
- What else can you do for me?
Start Agent Health
Now that you have the infrastructure running, you can start OpenSearch Agent Health locally and connect it to your cloud resources.
The CDK infrastructure deployment created a file cdk-output.json, which contains all relevant configuration values for Agent Health. We’ve already created a file agent-health/agent-health.config.ts that pulls these values dynamically in your environment, so you can start Agent Health without any further configuration.
Open a terminal and start Agent Health by running the following command:
Open http://localhost:4001 in your browser to access Agent Health UI. Choose Agent Traces in the sidebar menu to access your agent’s traces. You should see traces from your previous interactions:
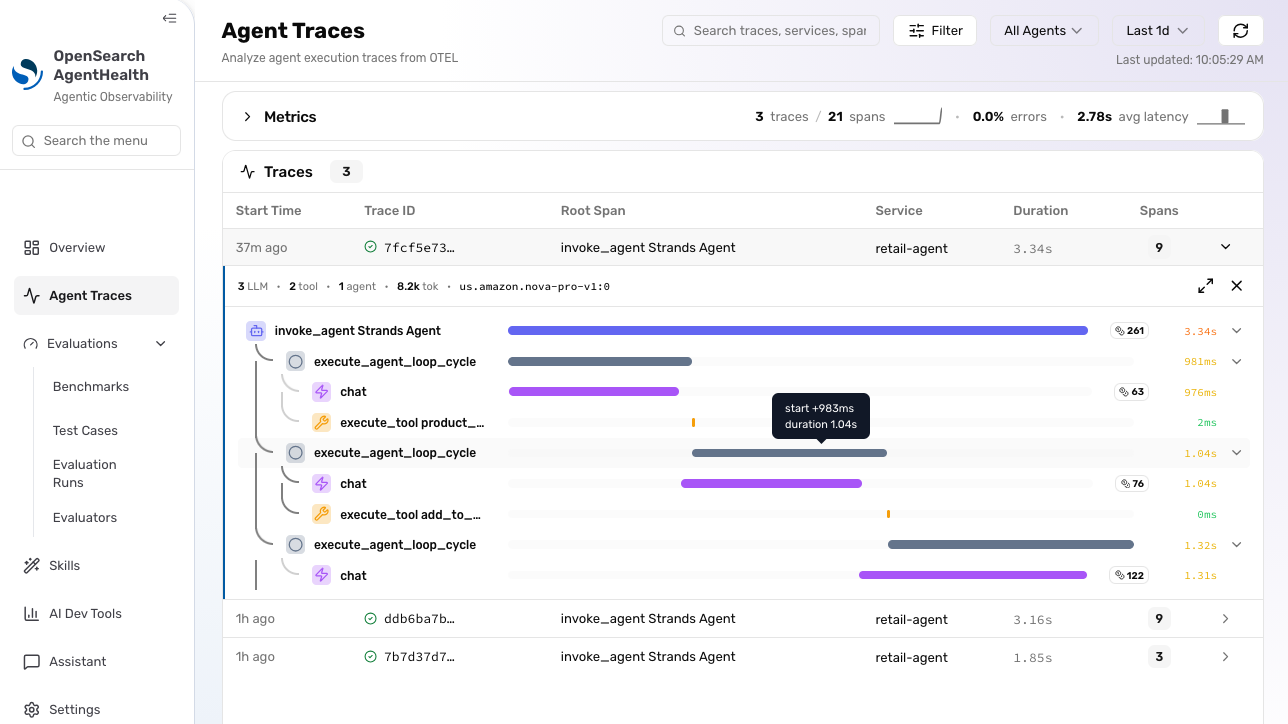
Figure 3: Agent traces. As Agent Health is in active development, this interface might have changed since the time of writing
Expand the trace and explore the information it contains, such as token count and agent trajectory (sequence of messages, reasoning steps, and tool calls).
If you’re unable to access the application or see any traces, verify the following:
- Check Agent Health logs in your terminal for any errors. Also check whether Agent Health is running on an alternative port, like 4002 instead of 4001.
- If there are permission errors when accessing traces from OpenSearch, verify that the AWS credentials in your terminal match the principal (user or role) that you specified under the
agentHealthReaderArnCDK parameter duringcdk deploy. This principal must haveESHttpGet:*IAM permissions. Agent Health uses your current AWS credentials to access the OpenSearch API for querying traces. The OpenSearch API is guarded by both IAM and OpenSearch fine-grained access control.
Create and run a test
Choose Test Cases and New Test Case. Fill out the required fields with the following information:
- Name: Should add to cart.
- Initial Prompt: Add some wireless headphones to my cart. Take any that you have in stock.
- Expected Outcomes: PROD-001 added to cart.
Back in the test cases overview, select the created test case and choose Run Test. In the Configure Run dialog, choose Retail Assistant (production) for Agent, Tool Usage Efficiency for Evaluator, Claude Opus 4.8 for Judge Model, and choose Start Run.
Agent Health now runs the configured initial prompt against the agent. The agent completes the task and sends execution traces to OpenSearch. Agent Health uses an evaluation model to check both agent responses and traces on successful execution, according to the defined expected outcomes. After the test is completed, go through the different tabs to check the test results.
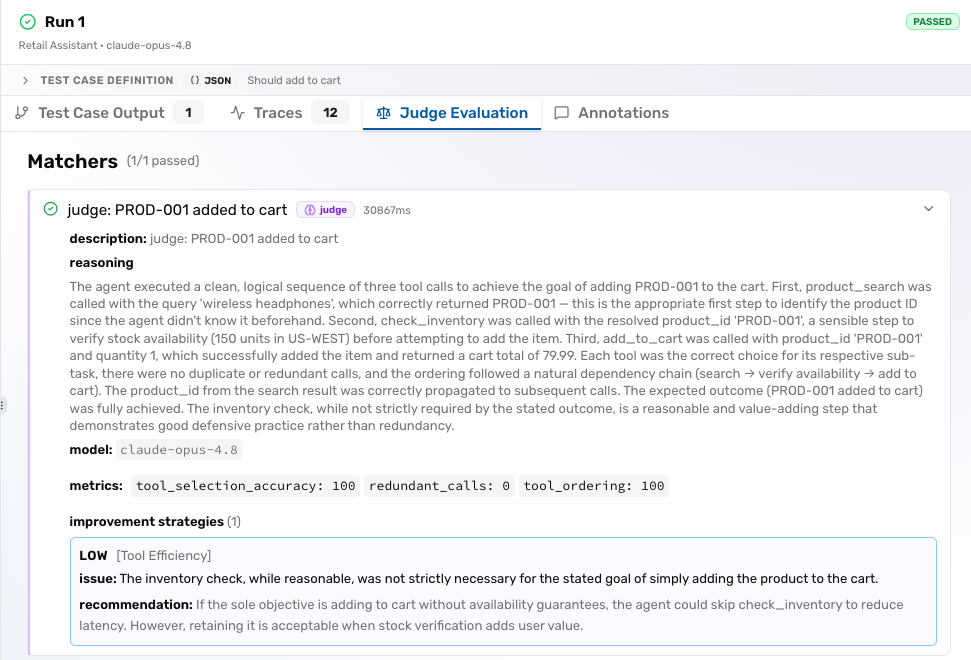
Figure 4: Agent Health evaluation report
If you’re unable to run the test, check the following:
- Agent Health automatically creates an Amazon Cognito token for your user upon start, but this token can expire. Restarting Agent Health creates a new token. Verify that both the
COGNITO_EMAILandCOGNITO_PASSWORDvariables are still set in your terminal environment.
Beyond test cases
After running a single test case, choose Benchmarks in the sidebar menu. With Benchmarks, you can run multiple test cases in parallel and summarize their results. You can compare benchmark runs by choosing Evaluation Runs in the sidebar, where you can analyze trends in pass rate, cost, and duration over time. Lastly, choose Evaluators to define your own evaluation logic beyond the predefined ones.
You can also run Agent Health tests with its command-line interface, which is handy for automation and continuous integration (CI). The equivalent command of running the preceding test is:
where TEST_CASE_ID can be retrieved from the browser URL when you visit the Agent Health UI (test case IDs start with tc-).
Agent Health stores all test cases, other configuration, and reports locally on disk in the agent-health/agent-health-data directory.
Cleaning up
To avoid incurring future charges, delete the resources:
Conclusion
In this post, you learned to set up and use OpenSearch Agent Health for production agent observability and evaluations. To discover more features, see the Agent Health documentation pages. You can discuss and request additional features, and get help with setup, through the issues in the GitHub project. For more information, see the observability documentation for Amazon OpenSearch Service, where you can learn about the features available to build observability for both agents and traditional systems using OpenSearch. To investigate issues in production AI agents, see the recent post Unified observability in Amazon OpenSearch Service.
About the authors
Accelerate Apache Spark debugging on Amazon EMR with AWS DevOps Agent
Post Syndicated from Kalyan Janaki original https://aws.amazon.com/blogs/big-data/accelerate-apache-spark-debugging-on-amazon-emr-with-aws-devops-agent/
When an Apache Spark job fails on Amazon EMR, the root cause can hide in executor logs, memory profiles, or application code. As data pipelines grow in complexity, correlating logs, metrics, and traces across multiple services requires significant operational effort. AWS DevOps Agent handles this investigation autonomously while keeping operators in the loop to review findings and approve fixes. From a single chat prompt, it produces a root cause and mitigation plan, often without any human involvement beyond the initial question.
The native AWS API tools in AWS DevOps Agent don’t extend into Spark-internal artifacts. Sometimes those tools can’t reach the evidence that pins down the root cause: a Spark History Server event log, executor Python worker memory, or a line of code that allocated too much. In these cases, AWS DevOps Agent can describe symptoms (“the executor exited with code 1”) but can’t identify the actual antipattern that caused them.
This post shows how to extend AWS DevOps Agent to investigate failures in Apache Spark workloads on Amazon EMR. You register the Apache Spark Troubleshooting Agent for Amazon EMR, a managed Model Context Protocol (MCP) server hosted by AWS, as a custom capability provider in your AWS DevOps Agent space. You route the traffic over AWS PrivateLink so MCP calls never traverse the public internet. Then you watch a single agent chat session investigate a deliberately failing Spark job, from Amazon CloudWatch alarm to line-numbered root cause, in about two minutes.
Prerequisites
Before you begin, make sure you have the following:
- An AWS account with permissions to deploy AWS CloudFormation stacks that create AWS Identity and Access Management (IAM) roles and Amazon Virtual Private Cloud (Amazon VPC) resources.
- The latest version of the AWS Command Line Interface (AWS CLI), Boto3, and Botocore, installed and configured with credentials for the same account and AWS Region.
- This walkthrough assumes you are familiar with AWS DevOps Agent and know how to trigger an investigation. For an introduction, see Getting started with AWS DevOps Agent.
How AWS DevOps Agent discovers custom tools through MCP
Model Context Protocol (MCP) is an open standard that defines how AI agents discover and invoke external tools. AWS DevOps Agent supports connecting to custom MCP servers, which means you can expose new capabilities to it without modifying the agent itself. When you connect an MCP server to AWS DevOps Agent, the agent automatically discovers the available tools, understands their schemas, and calls them as part of its investigation workflow. You build and connect the MCP server, and the agent handles the rest.
MCP tools sit alongside the agent’s built-in AWS API tools. During a single investigation, the agent can interleave calls to cloudwatch.describe-alarms, emr-serverless.get-job-run, and a custom MCP tool such as analyze_spark_workload. The agent picks the right one for each subtask. You augment the agent’s reach without replacing what it already does.
For this integration, you don’t build an MCP server. The Apache Spark Troubleshooting Agent for Amazon EMR is itself a managed MCP server, hosted by AWS at a regional endpoint. Your job is to register that endpoint with AWS DevOps Agent and authorize the agent to call it. This requires a network path from the agent to the endpoint, plus an IAM role for AWS Signature Version 4 request signing.
Why Spark internals visibility matters
The actual root cause for a Spark failure usually lives somewhere none of those APIs (such as Amazon CloudWatch Logs Insights, AWS CloudTrail, or Amazon EMR step-status calls) can reach:
The Apache Spark Troubleshooting Agent for Amazon EMR reads the following sources.
The Spark History Server event log is a per-job archive in Amazon Simple Storage Service (Amazon S3) with stage timings, task-level metrics, executor utilization, shuffle read/write volumes, and garbage-collection pauses. Amazon EMR exposes this data through the Spark UI on Amazon EMR Serverless, Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2), and Amazon EMR on Amazon Elastic Kubernetes Service (Amazon EKS), but interpreting signals like data skew, executor memory pressure, or stages that take significantly longer than expected requires familiarity with Spark internals.
- The Spark query plan — the logical and physical plan the driver compiled. Without it, you can’t identify antipatterns such as unnecessary data repartitioning or missing broadcast hints that trigger expensive shuffles.
- The application source code in Amazon S3 — the
.pyor.jarcode artifact the job ran. Without it, you can’t quote the offending line of amapPartitionsuser-defined function or an inefficientcollect(). - The Python worker process telemetry — the PySpark worker is a separate Python subprocess outside the Java Virtual Machine’s (JVM) managed memory. When it crashes from
spark.executor.pyspark.memoryexhaustion, the JVM driver sees a generic “executor exited unexpectedly” message. The actual cause is invisible to standard JVM-level logs.
When the agent invokes analyze_spark_workload during an investigation, it returns a structured analysis with the antipattern identified at the line level, the offending stage isolated, and a concrete fix: both code changes and configuration changes.
Integrating AWS DevOps Agent with Apache Spark Troubleshooting MCP
This section explains how AWS DevOps Agent connects to the Apache Spark Troubleshooting Agent through a private MCP endpoint and orchestrates the investigation workflow.
How it works
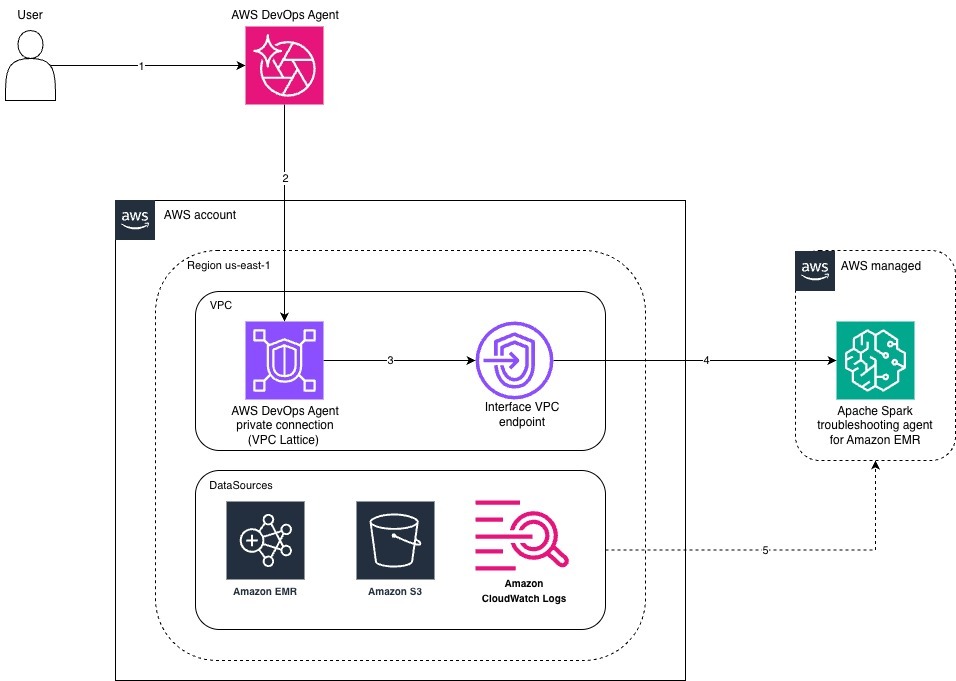
Figure 1: Integration architecture between AWS DevOps Agent and the Apache Spark Troubleshooting Agent for Amazon EMR over AWS PrivateLink
- You submit an investigation prompt in AWS DevOps Agent.
- AWS DevOps Agent sends a SigV4-signed MCP call into your Amazon VPC through the AWS DevOps Agent private connection.
- The private connection forwards the request to the Interface VPC Endpoint.
- The endpoint routes the request over AWS PrivateLink to the Apache Spark Troubleshooting Agent for Amazon EMR, which AWS manages.
- The MCP service reads from your data sources (Amazon EMR, Amazon S3, Amazon CloudWatch Logs) using the same IAM role AWS DevOps Agent assumed for the call.
- When a CloudWatch alarm transitions to ALARM state (for example, a failed-jobs alarm for your Amazon EMR Serverless application), AWS DevOps Agent automatically triggers an investigation without manual intervention.
- AWS DevOps Agent decides which tools to call based on the prompt. For a Spark failure, that includes the Apache Spark Troubleshooting MCP server you registered as a capability provider.
- Each MCP request is signed with AWS Signature Version 4 using the IAM role assigned to the capability provider. The request travels from AWS DevOps Agent into your Amazon VPC through the private connection. This private connection is a managed VPC Lattice resource gateway you created during setup.
- From the resource gateway, the request flows to the Interface VPC Endpoint for the Amazon SageMaker Unified Studio MCP service, then on to the Apache Spark Troubleshooting Agent. The traffic stays entirely on the AWS network.
- The MCP server reads the inputs it needs from your AWS account using the IAM role that you assigned to the capability provider during MCP server registration. This role grants access to the Spark History Server event log and application source code in Amazon S3, the driver and executor stdout streams in Amazon CloudWatch Logs, and the job-run metadata from Amazon EMR Serverless.
- The MCP server returns its diagnostic findings to AWS DevOps Agent. The agent then analyzes the results, identifies the root cause, and presents recommended fixes both code-level and configuration-level in your chat.
Setting up the demo
As part of this demo, this post includes a sample AWS CloudFormation template, tested in the us-east-1 Region, that provisions the following resources for the walkthrough:
- A dedicated Amazon Virtual Private Cloud (Amazon VPC) with two private subnets in Availability Zones supported by the Apache Spark Troubleshooting Agent for Amazon EMR.
- An Interface VPC Endpoint for the Apache Spark Troubleshooting Agent for Amazon EMR.
- An IAM role that AWS DevOps Agent assumes to invoke the Apache Spark Troubleshooting MCP server with AWS Signature Version 4.
- A deliberately failing PySpark workload running on Amazon EMR Serverless, including the Amazon EMR Serverless application, the Spark execution role, and the demo logs stored in Amazon S3 bucket.
- An Amazon CloudWatch alarm that fires when the demo job fails. This alarm is used as the trigger for the agent investigation later in this section.
Step 1: Clone the repository
Clone the git repository for the CloudFormation template, PySpark script, and Parquet data.
Step 2: Deploy the AWS CloudFormation stack
Deploy the template using the following AWS CLI command.
The stack reaches CREATE_COMPLETE in approximately 4–6 minutes. When it does, capture the following stack outputs, which you paste into the AWS DevOps Agent console in the next two steps:
DemoVpcId— the VPC ID for the AWS DevOps Agent private connection.DemoSubnetIds— the two subnet IDs for the AWS DevOps Agent private connection.SMUSVpcEndpointSecurityGroupId— the security group ID.TroubleshootingRoleArn— the IAM role Amazon Resource Name (ARN).MCPEndpointURL— the MCP endpoint URL to register.FailedJobsAlarmName— the CloudWatch alarm name to reference in your investigation prompt.DemoBucket— the S3 bucket name where you copy the demo script and Parquet data.
To retrieve all outputs at once, use the following AWS CLI command.
Step 3: Create an agent space
The agent space defines which AWS account and Region the agent monitors, which IAM role it assumes, and which capability providers, including MCP servers, it can call.
Follow the steps in Creating an Agent Space in the AWS DevOps Agent User Guide. When completing those steps, use the following values:
| Parameter | Value |
| Name | data-pipeline-troubleshooting |
| Region | us-east-1 |
| Agent Space role | Choose Auto-create a new DevOps Agent role — the console generates a DevOpsAgentRole-AgentSpace* role with AIOpsAssistantPolicy attached |
| Optional integrations | Not required |
After the agent space reaches Active status, proceed to create the private connection.
Step 4: Create the AWS DevOps Agent private connection
AWS DevOps Agent uses the private connection to reach into your Amazon VPC. Follow the steps in Connecting to privately hosted tools in the AWS DevOps Agent User Guide. You can use either the console or the AWS CLI command documented under Create a private connection.
When completing those steps, use the following values from your CloudFormation stack outputs:
| Parameter | Value |
| Name | A descriptive name (for example, spark-private) |
| VPC | DemoVpcId from your stack outputs |
| Subnets | Both subnet IDs from DemoSubnetIds |
| Security group | SMUSVpcEndpointSecurityGroupId |
| TCP port ranges (Advanced configuration) | 443 |
| Host address (Service target details) | sagemaker-unified-studio-mcp.us-east-1.api.aws |
| DNS resolution | In VPC (private DNS) |
| Certificate public key | None |
After the connection reaches Active status, proceed to Step 5.
Step 5: Register the Apache Spark Troubleshooting MCP server as a capability provider
With the private connection in place, register the MCP server as a capability provider. Follow the steps in Registering an MCP server at the account level in the AWS DevOps Agent User Guide.
When completing those steps, use the following values:
| Parameter | Value |
| Name | spark-troubleshooting |
| Endpoint URL | MCPEndpointURL from your stack outputs |
| Connect to endpoint using a private connection | Selected |
Step 6: Add the MCP server to the agent space
With the MCP server registered, you need a workspace where investigations run. The agent space defines which AWS account and Region the agent monitors, which IAM role it assumes, and which capability providers, including MCP servers, it can call.
- In the MCP Server section, choose Add.
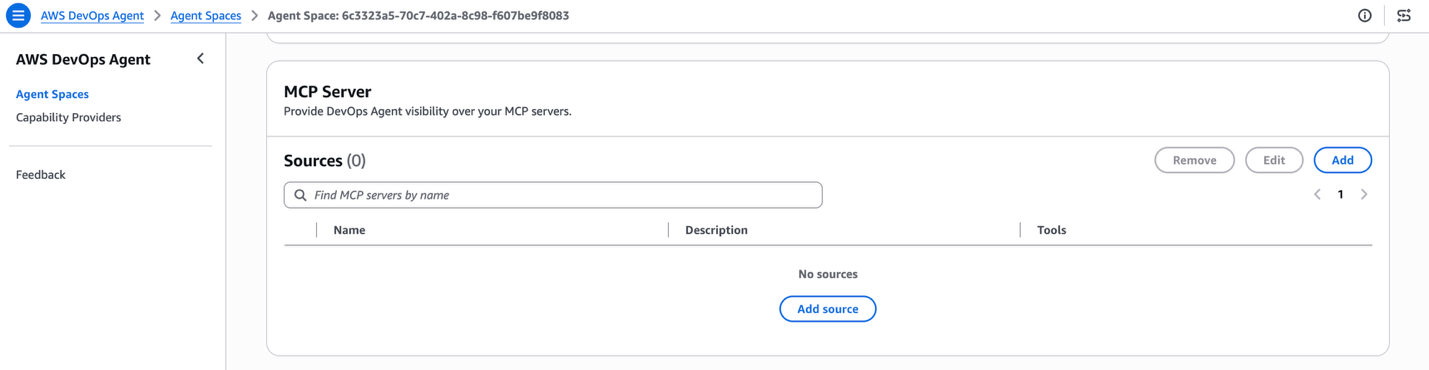
Figure 2: MCP Server section of the agent space detail page
- In the Add a capability dialog, locate
spark-troubleshootingin the list of registered MCP servers and choose Add.
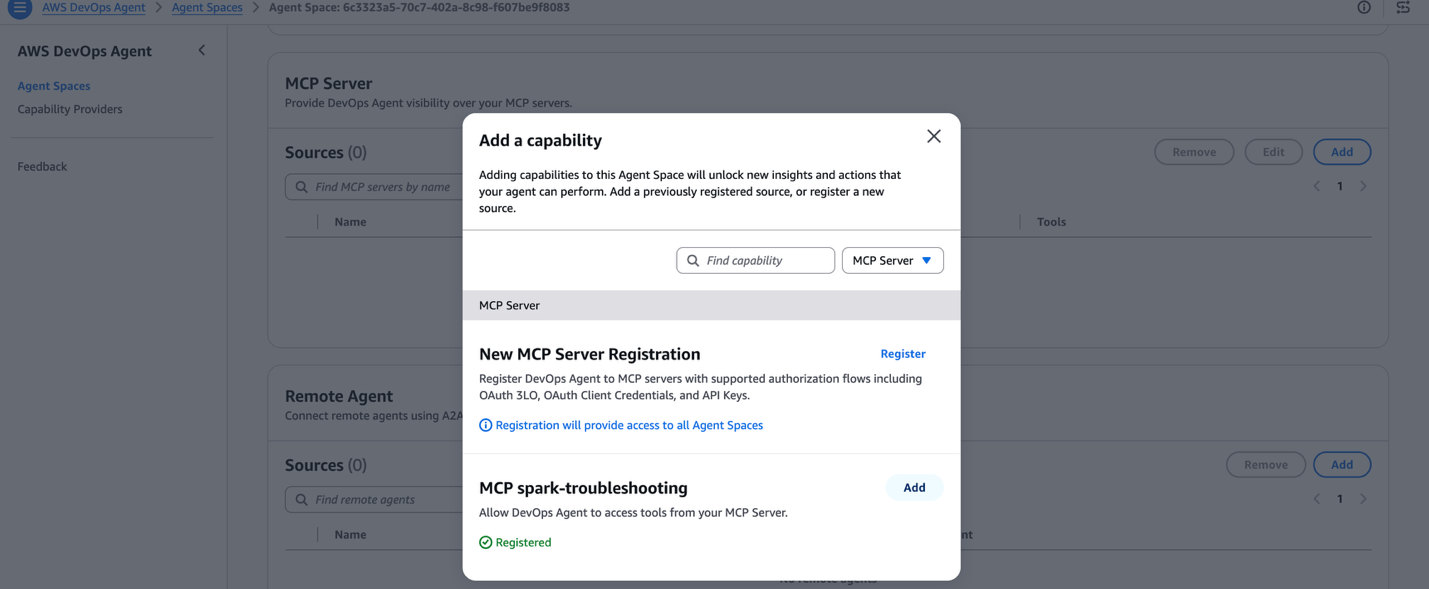
Figure 3: Add a capability with the spark-troubleshooting MCP server listed
- On the Select MCP server tools page, both tools that the Apache Spark Troubleshooting Agent for Amazon EMR publishes are listed:
analyze_spark_workloadandanalyze_spark_history_server_endpoint. Select both checkboxes, then choose Save.
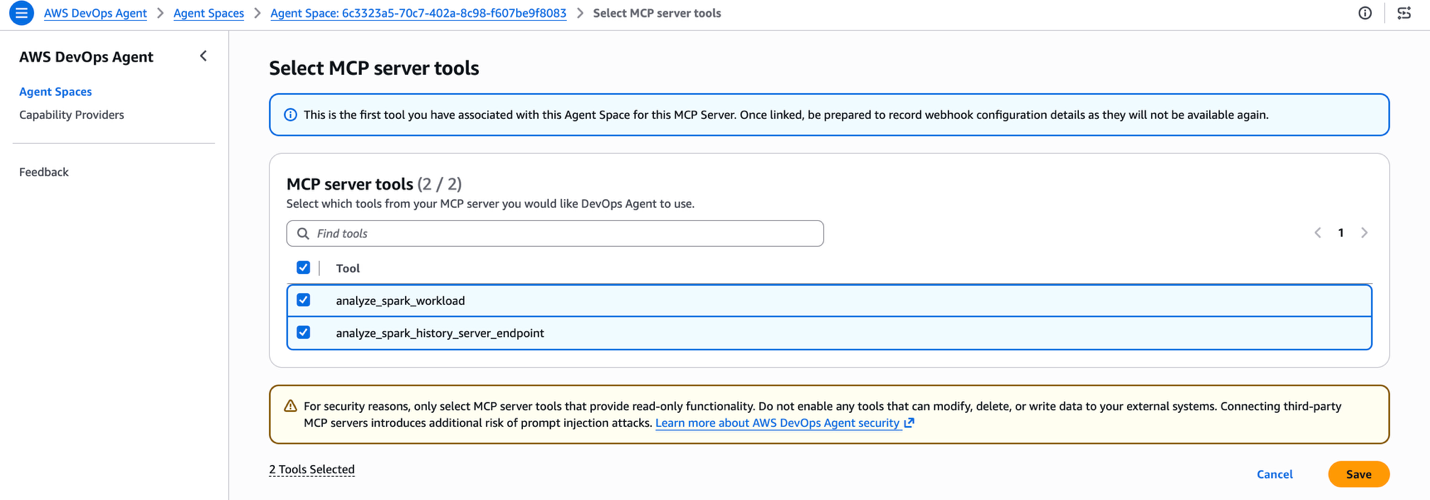
Figure 4: The Select MCP server tools page with both Spark troubleshooting tools selected
The agent space connects to the MCP server, lists its tools, and displays 2 Available / 2 Connected. Both tools are now part of your agent’s catalog.
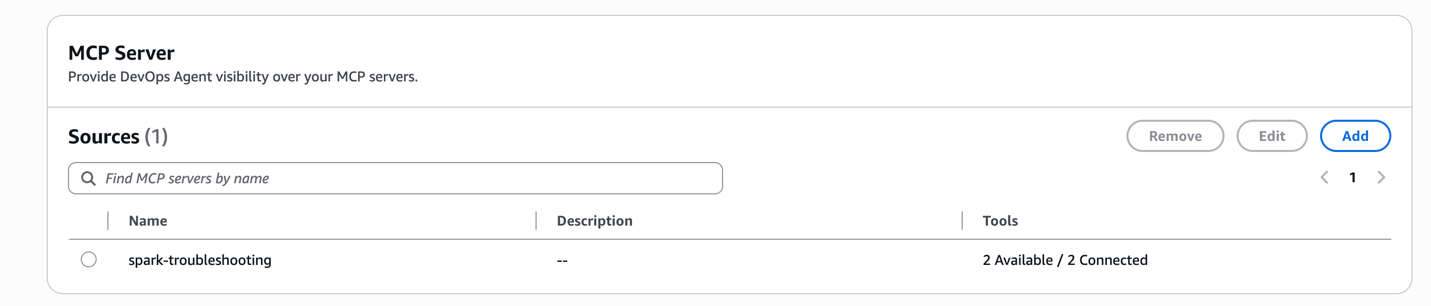
Figure 5: MCP Server section showing spark-troubleshooting connected with both tools available
Seeing it in action
To see the integration end to end, you submit a PySpark job, watch the CloudWatch alarm move to ALARM, and then ask AWS DevOps Agent to investigate using the alarm name.
The failing workload
The CloudFormation template provisioned an Amazon EMR Serverless application called analytics-events-platform and configured a sample PySpark job, customer_events_aggregator.py. The script simulates a common Python-side memory bug: a mapPartitions user-defined function accumulates 11 copies of every input row in an in-memory Python list before yielding results, while the job runs with spark.executor.pyspark.memory=256m. The Python worker process exceeds the 256 MB cap, the kernel kills it, Spark retries four times, and the stage is marked failed.
Submit the failing job
Run the DemoSubmitJobCommand from your stack outputs in your terminal. It looks like this:
The command returns a jobRunId. Note it down. You will see it later in the agent’s investigation.
The job goes through PENDING to SCHEDULED to RUNNING to FAILED and reaches FAILED state in roughly four minutes.
Watch the CloudWatch alarm fire
The CloudFormation template also created a CloudWatch alarm named <DemoApplicationId>-FailedJobs (the exact name is in the FailedJobsAlarmName stack output). The alarm watches the FailedJobs metric in the AWS/EMRServerless namespace, scoped to your demo application, and flips to ALARM within a minute or two of the job failing.
Open the Amazon CloudWatch console, choose Alarms in the left navigation pane, and confirm the alarm is in In alarm state.
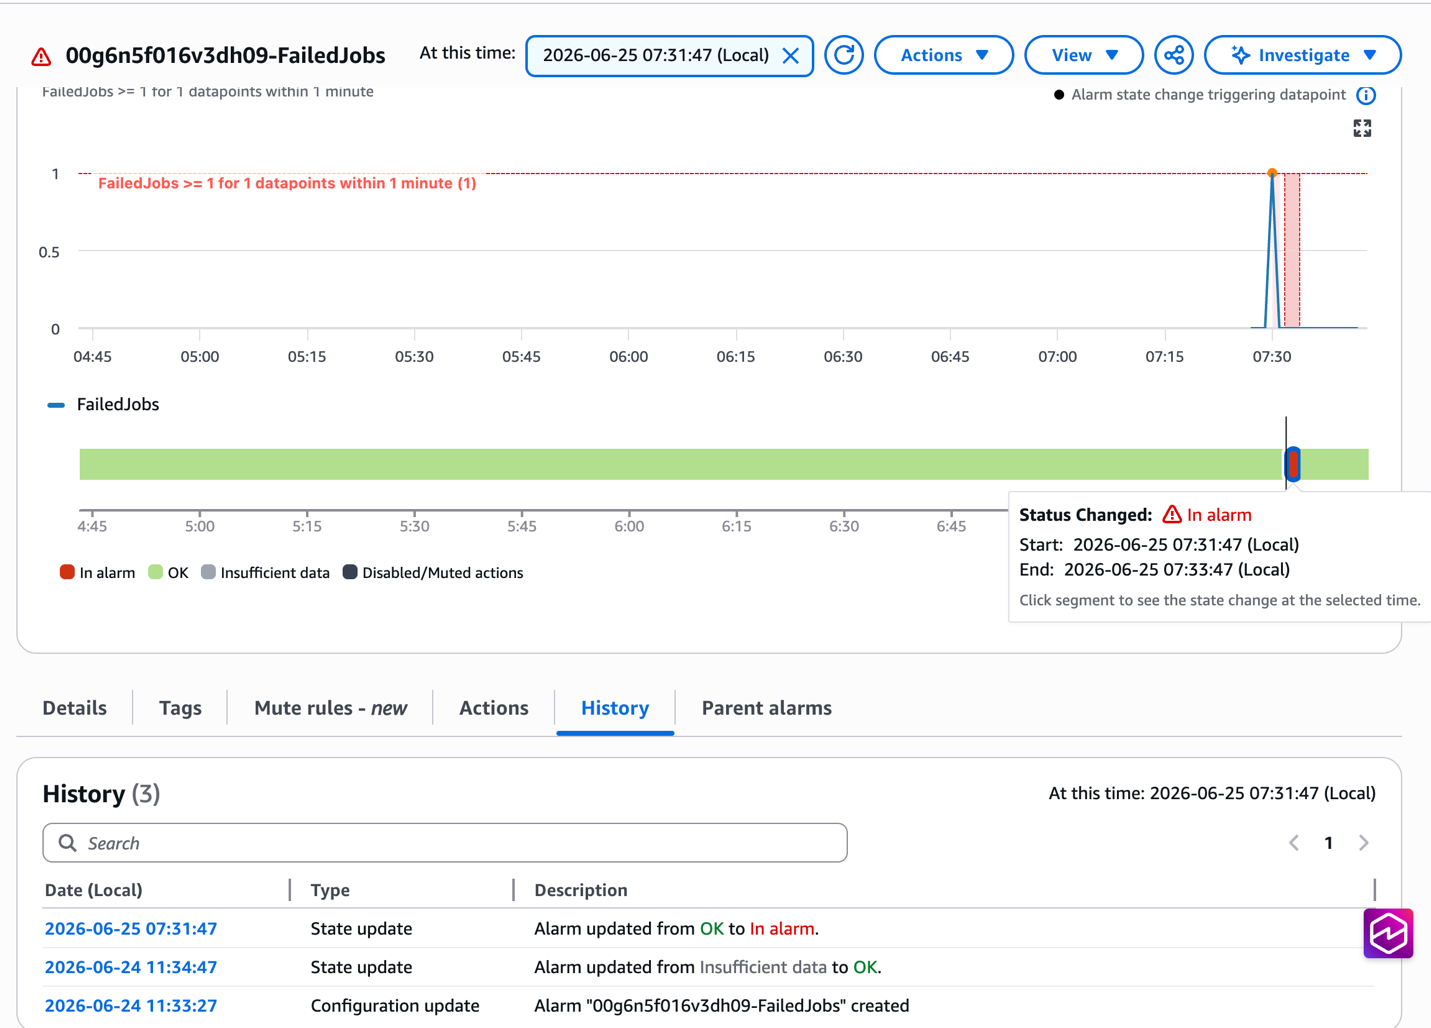
Figure 6: The Amazon CloudWatch alarm detail page showing the FailedJobs alarm in the In alarm state
Ask AWS DevOps Agent to investigate
- Open your AWS DevOps Agent space.
- In the left navigation pane, choose Operator Access, then choose Incidents.
- Choose Start an investigation.
- Paste the following prompt, replacing
<FailedJobsAlarmName>with the value from your stack outputs:
CloudWatch alarm in us-east-1 just went into ALARM state. Investigate why and recommend a fix
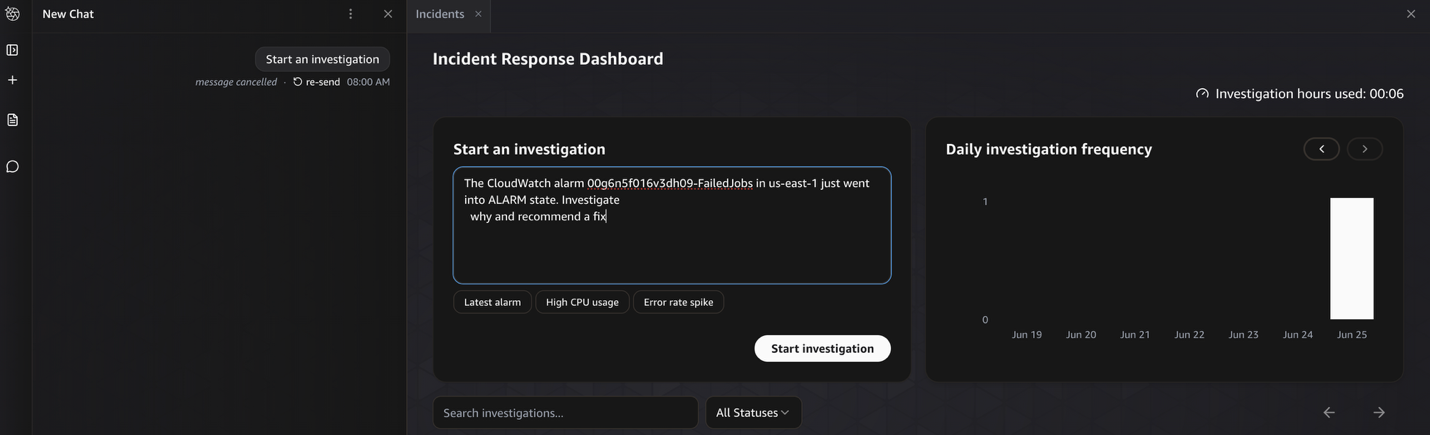
Figure 7: AWS DevOps Agent Start an investigation panel with the Amazon CloudWatch alarm investigation prompt
The agent’s investigation chains together native AWS API tools and the Apache Spark Troubleshooting MCP tool you registered:
use_aws cloudwatch describe-alarms— fetches the alarm definition and reads its metric dimensions, identifying that the alarm is scoped to Amazon EMR Serverless application<DemoApplicationId>.use_aws emr-serverless list-job-runs— finds the most recent FAILED job run on that application.use_aws emr-serverless get-job-run— pulls the FAILED run’s metadata and last-known error.spark-troubleshooting analyze_spark_workload— invokes the Apache Spark Troubleshooting Agent for Amazon EMR through the MCP capability provider, passing the application ID and job run ID. This is where the deep analysis happens.
Review the root cause and fix
When the investigation completes, AWS DevOps Agent presents the results across two tabs: Investigation timeline and Root cause.
The Investigation timeline shows every step the agent took: skills loaded, native AWS API calls made, and the moment it called the analyze_spark_workload MCP tool to analyze the failed Spark job. Each entry is expandable so you can audit the inputs and outputs.
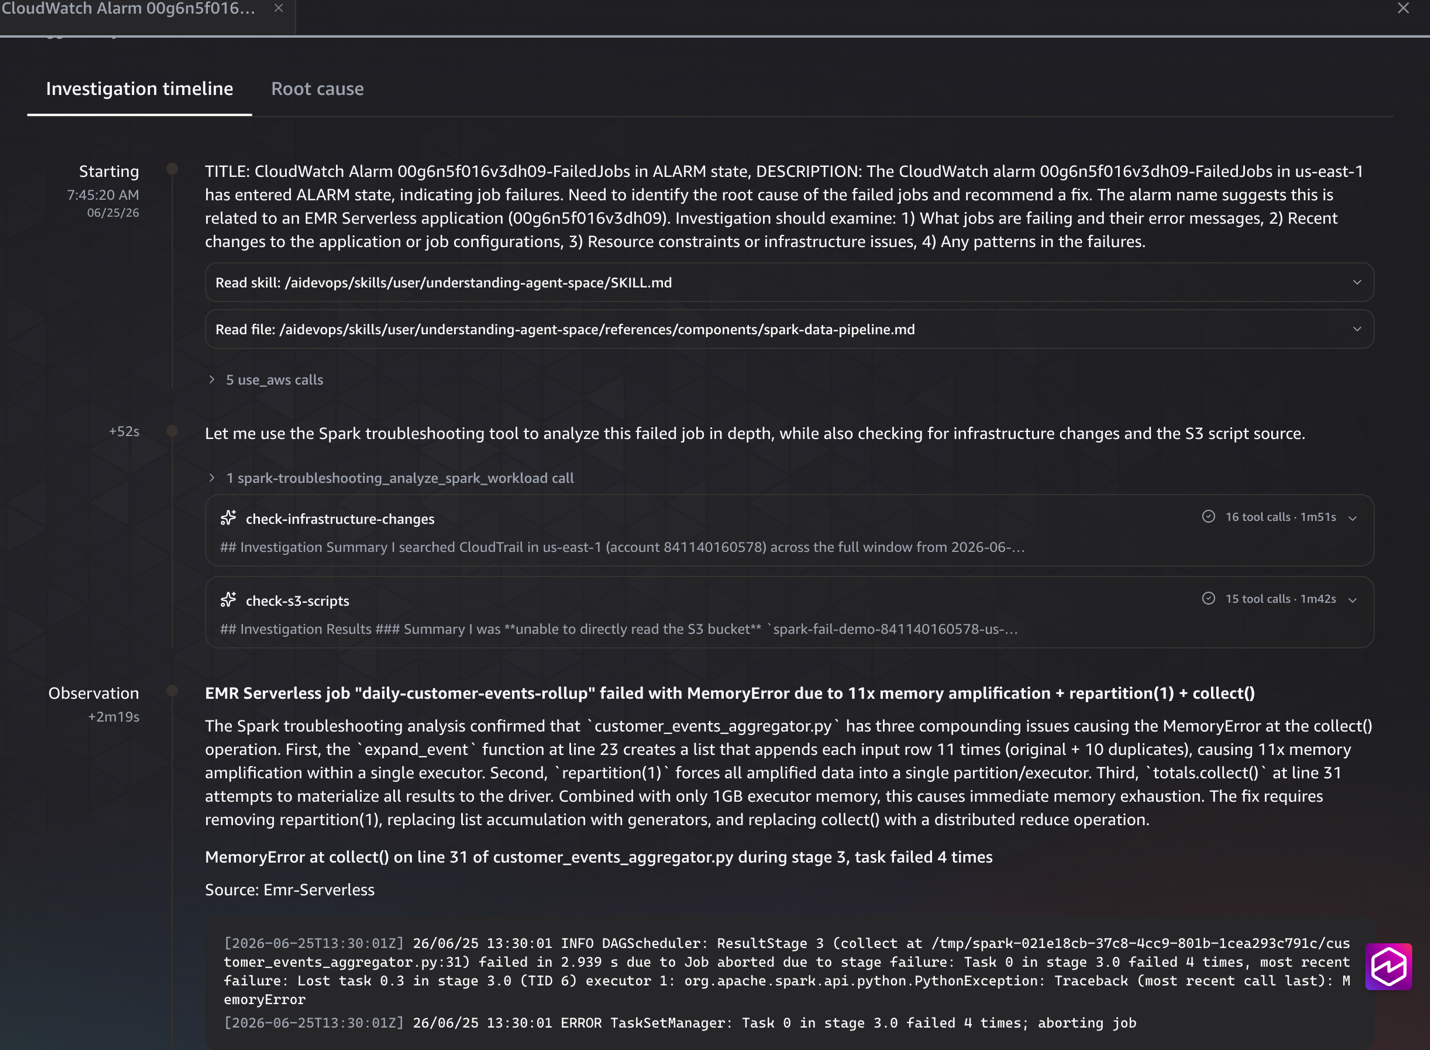
Figure 8: Investigation timeline tab showing the sequence of agent tool calls and the spark-troubleshooting MCP invocation
The Root cause tab is where the answer lands. It is organized into three sections that mirror what an experienced engineer would write in an incident report:
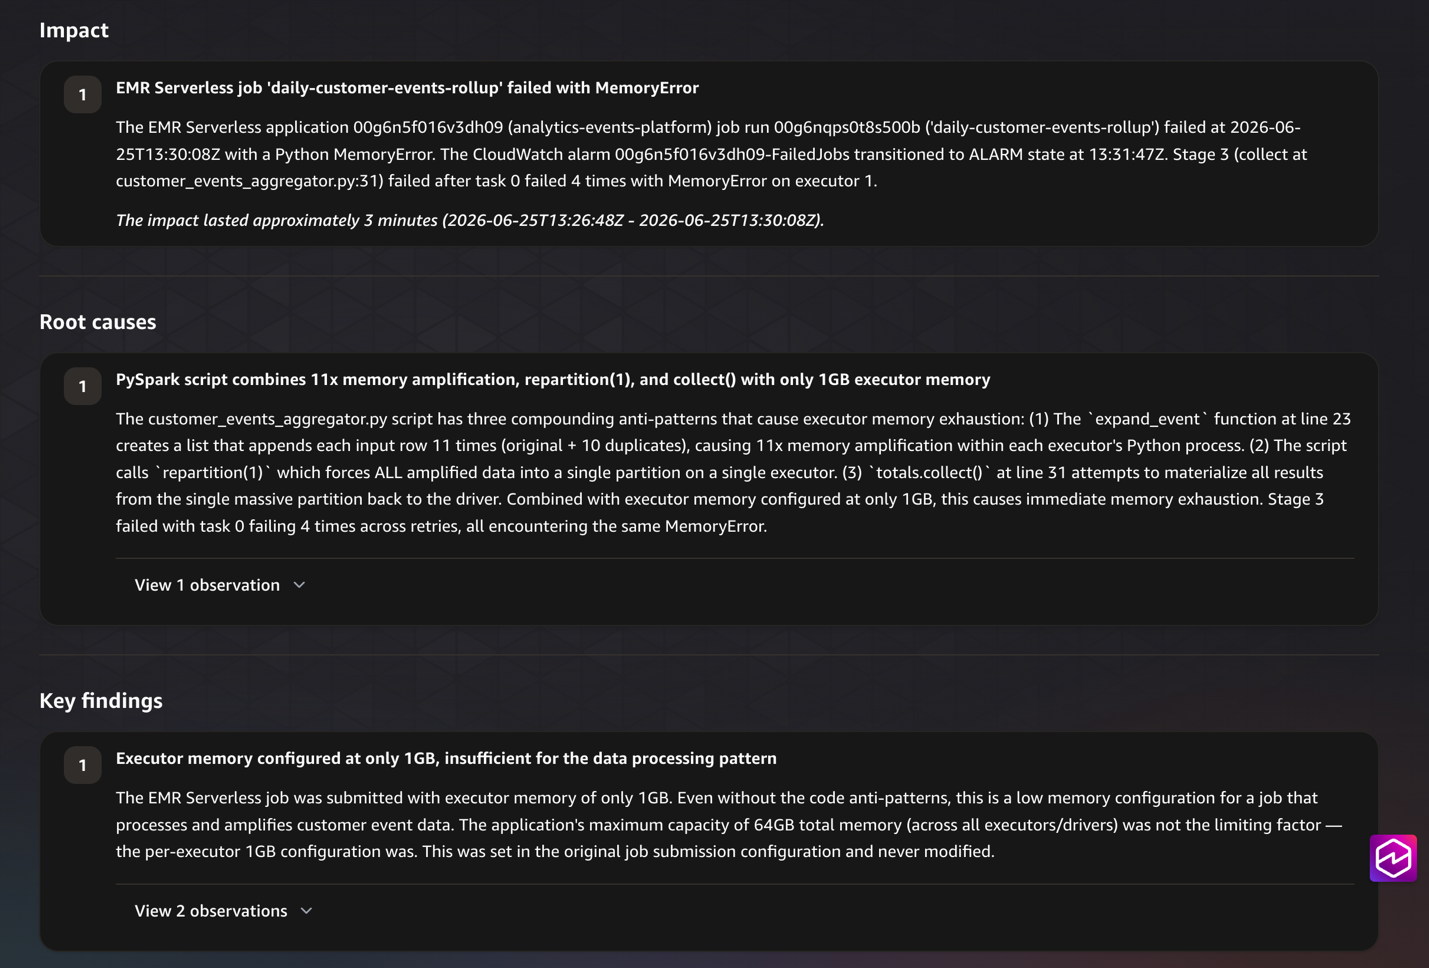
Figure 9: The Root cause tab showing the impact summary, identified root causes, and key findings for the Spark memory exhaustion failure
- Impact — what failed, when, and for how long. For our demo, this calls out that the
daily-customer-events-rollupjob on theanalytics-events-platformapplication failed with aMemoryErrorand that the alarm transitioned to ALARM state at the time of the failure. - Root causes — the actual antipattern. The agent identifies that
customer_events_aggregator.pycombines three compounding issues: anexpand_eventfunction (line 23) that amplifies each input row 11×, arepartition(1)that funnels all data into a single partition on a single executor, and acollect()(line 31) that pulls the amplified dataset back to the driver. All three run with only 1 GB of executor memory. - Key findings — supporting facts behind the diagnosis, including the executor memory configuration, the application’s maximum capacity, and how the agent confirmed each fact from the analyzed artifacts.
Both the antipattern identification and the supporting evidence come from artifacts the agent could only reach through the MCP tool: the application source code in Amazon S3, the Spark History Server event log, and the query plan. Without the Apache Spark Troubleshooting Agent for Amazon EMR plugged in, AWS DevOps Agent would have stopped at “the executor exited with a memory error.”
Clean up
To avoid ongoing charges, delete the resources you created. Some resources are managed by the AWS DevOps Agent console and must be removed there first. Otherwise, the CloudFormation stack deletion fails.
- In the AWS DevOps Agent console, open your
data-pipeline-troubleshootingagent space, choose the MCP Server section, selectspark-troubleshooting, and choose Remove. - From the Agent spaces list, select
data-pipeline-troubleshootingand choose Delete. - In Capability Providers, select
spark-troubleshootingand choose Deregister. - In Capability Providers → Private connections, select
smus-spark-privateand choose Delete. - Delete the AWS CloudFormation stack. This removes the Amazon VPC, the Interface VPC Endpoint, the security group, the IAM role, the Amazon EMR Serverless application, the Spark execution role, the Amazon CloudWatch alarm, and the demo logs bucket.
Conclusion
In this post, you connected the Apache Spark Troubleshooting Agent for Amazon EMR to AWS DevOps Agent as a custom MCP capability provider. You kept the traffic on the AWS network with AWS PrivateLink, and ran a failing PySpark job to see the integration end to end. A CloudWatch alarm fired, you asked the agent to investigate, and a single chat session returned the root cause along with code and configuration fixes.
You can extend this pattern beyond the demo scenario. Consider connecting the MCP server to agent spaces that monitor your production Amazon EMR environment. Any Spark job that writes a History Server event log becomes diagnosable through the same workflow.
To continue learning, explore the following resources:
- AWS DevOps Agent documentation — learn how to create agent spaces, configure integrations, and manage investigations.
- Apache Spark Troubleshooting Agent for Amazon EMR setup guide — detailed prerequisites and configuration options for the MCP server.
- Connecting MCP servers to AWS DevOps Agent — register additional MCP servers to expand your agent’s capabilities.
- Sample code on GitHub — clone the CloudFormation template, PySpark script, and Parquet data used in this walkthrough.
If you’ve already integrated the Apache Spark Troubleshooting Agent into your operational workflow, or if you’re exploring other MCP-based extensions for AWS DevOps Agent, we want to hear about your experience. Share your thoughts and questions in the comments.
About the authors
[$] A pause for the Python JIT
Post Syndicated from jzb original https://lwn.net/Articles/1090385/
In 2024 the Python 3.13
release added an experimental
just-in-time (JIT) compiler to optimize the way that CPython executes Python
code. Since then, work has proceeded on the JIT, albeit perhaps less formally
than some might like. In June, Python’s steering
council (SC) put out an announcement
that no new development on the JIT land (with the exception of bug and security
fixes) in Python’s main branch, until it accepts a Python Enhancement Proposal (PEP)
that would make the case for the JIT as a supported part of CPython. That has
led to the creation of PEP 836 (“JIT Go Brrr: The
Path to a Supported JIT Compiler for CPython”), which is currently under
discussion. As it stands, it seems likely that work on JIT will continue, but
when that will happen is less certain.
Firefox 155 released
Post Syndicated from jzb original https://lwn.net/Articles/1091926/
Version
155 of the Firefox web browser has been released. Notable changes include a
count in the address bar of how many ad trackers Firefox has blocked, container
reordering, and ensuring that mailto: links are only opened by explicit
user actions. There is also a change of the domain used for “captive portals”
(such as the ones used to sign into hotel WiFI): Firefox now uses
“firefox-portal-detection.com” instead of “detectportal.firefox.com”, which may
require a change in network allow lists.
The release also includes a number of changes
that may impact web developers, as well as a number of bug fixes and security
fixes.
Hybrid cloud orchestration: Modernizing on-premises infrastructure management with AWS
Post Syndicated from Sandeep Singh original https://aws.amazon.com/blogs/architecture/hybrid-cloud-orchestration-modernizing-on-premises-infrastructure-management-with-aws/
This post demonstrates how to build a hybrid cloud orchestration solution that manages distributed on-premises infrastructure at scale using AWS serverless technologies. If you manage geographically dispersed data centers with thousands of servers that require bare-metal configuration, deployment, and ongoing lifecycle management, this solution provides centralized control while maintaining on-premises execution. Many of these environments also need the Kubernetes control plane itself to stay on-premises. This can be for data sovereignty, regulatory, or policy reasons, or because the network to AWS is disconnected, disrupted, intermittent, or limited (DDIL). Amazon EKS Anywhere runs the entire cluster on your own hardware, and this solution orchestrates it at scale from AWS. For on-premises workloads that can use a managed Amazon Elastic Kubernetes Service (Amazon EKS) control plane in the cloud, Amazon EKS Hybrid Nodes is the recommended approach.
In Part 1 of this series, you’ll learn the core architecture patterns for building an event-driven orchestration engine using AWS Lambda, AWS Step Functions, and Amazon DynamoDB. With this foundation, you can automate server lifecycle management through vendor-agnostic APIs, deploy EKS Anywhere clusters consistently across sites, and establish centralized observability for your entire infrastructure. In subsequent posts, we walk through the implementation with code examples, deployment templates, and detailed workflows for server and cluster management.
The challenge: Managing distributed on-premises infrastructure at scale
Managing distributed on-premises infrastructure at scale presents these challenges:
Inconsistency across locations: Different hardware vendors, network architectures, and compliance requirements lead sites to develop their own procedures. The same Kubernetes cluster deployment can produce different results at each site, such as the cluster version installed or the set of add-ons enabled. Without centralized orchestration, identical operations succeed at some locations but fail at others.
Manual lifecycle bottlenecks: The infrastructure lifecycle spans multiple layers requiring manual intervention. Hardware operations include BIOS configuration, firmware updates, and power management. OS operations cover installation and patching. Kubernetes operations encompass cluster creation, version upgrades, and scaling. Application operations involve deployment and maintenance. While manageable for individual servers, these processes become overwhelming bottlenecks when multiplied across thousands of geographically distributed machines.
Fragmented visibility: When management tools operate independently at each site, aggregating data across the entire environment becomes challenging. Operators struggle to answer enterprise-wide questions: How many servers are running outdated firmware? Which clusters are approaching capacity? Without centralized observability, identifying issues and planning capacity requires manual investigation across multiple locations.
Scalability limitations: Orchestration tools designed for a single data center encounter fundamental limitations at enterprise scale. Coordination mechanisms that work for dozens of servers fail when managing thousands. State synchronization becomes unreliable. Maintenance windows that are straightforward for a single site become logistical challenges across hundreds of locations.
Core technologies for hybrid orchestration
To address these operational challenges, four core technologies work together to deliver centralized orchestration with distributed execution:
Hybrid connectivity: Secure network connectivity between AWS and on-premises sites forms the foundation for centralized orchestration. AWS Direct Connect provides dedicated private connections, while AWS Site-to-Site VPN offers encrypted tunnels over the internet. This connectivity allows AWS services running in your virtual private cloud (VPC) to coordinate lifecycle operations with on-premises infrastructure.
AWS architecture stack: The AWS serverless stack along with Amazon EventBridge sets the foundation for an event-driven orchestration engine. Additional compute services include AWS CodeBuild for build processes, AWS Batch for long-running jobs, and AWS Systems Manager for on-premises tasks. These services provide a framework that can handle different execution runtimes while AWS manages the underlying infrastructure.
Redfish APIs: Redfish (a standard protocol for hardware management developed by the DMTF) delivers vendor-agnostic APIs for hardware management, allowing standardized control of bare-metal servers. Through Redfish, BIOS configuration, firmware updates, power management, and health monitoring operations are executed across diverse hardware environments.
Amazon EKS Anywhere: EKS Anywhere creates and operates Kubernetes clusters on your own infrastructure, using the same Amazon EKS Distro that powers Amazon EKS in the cloud. It supports several infrastructure providers, including the bare-metal provider this solution uses. Cluster lifecycle operations and maintenance are your responsibility, which is the work the orchestration engine automates across sites. If you have on-premises or edge environments with reliable connectivity to an AWS Region, Amazon EKS Hybrid Nodes is the recommended alternative. For the full set of options, see Amazon EKS deployment options.
Architecture overview
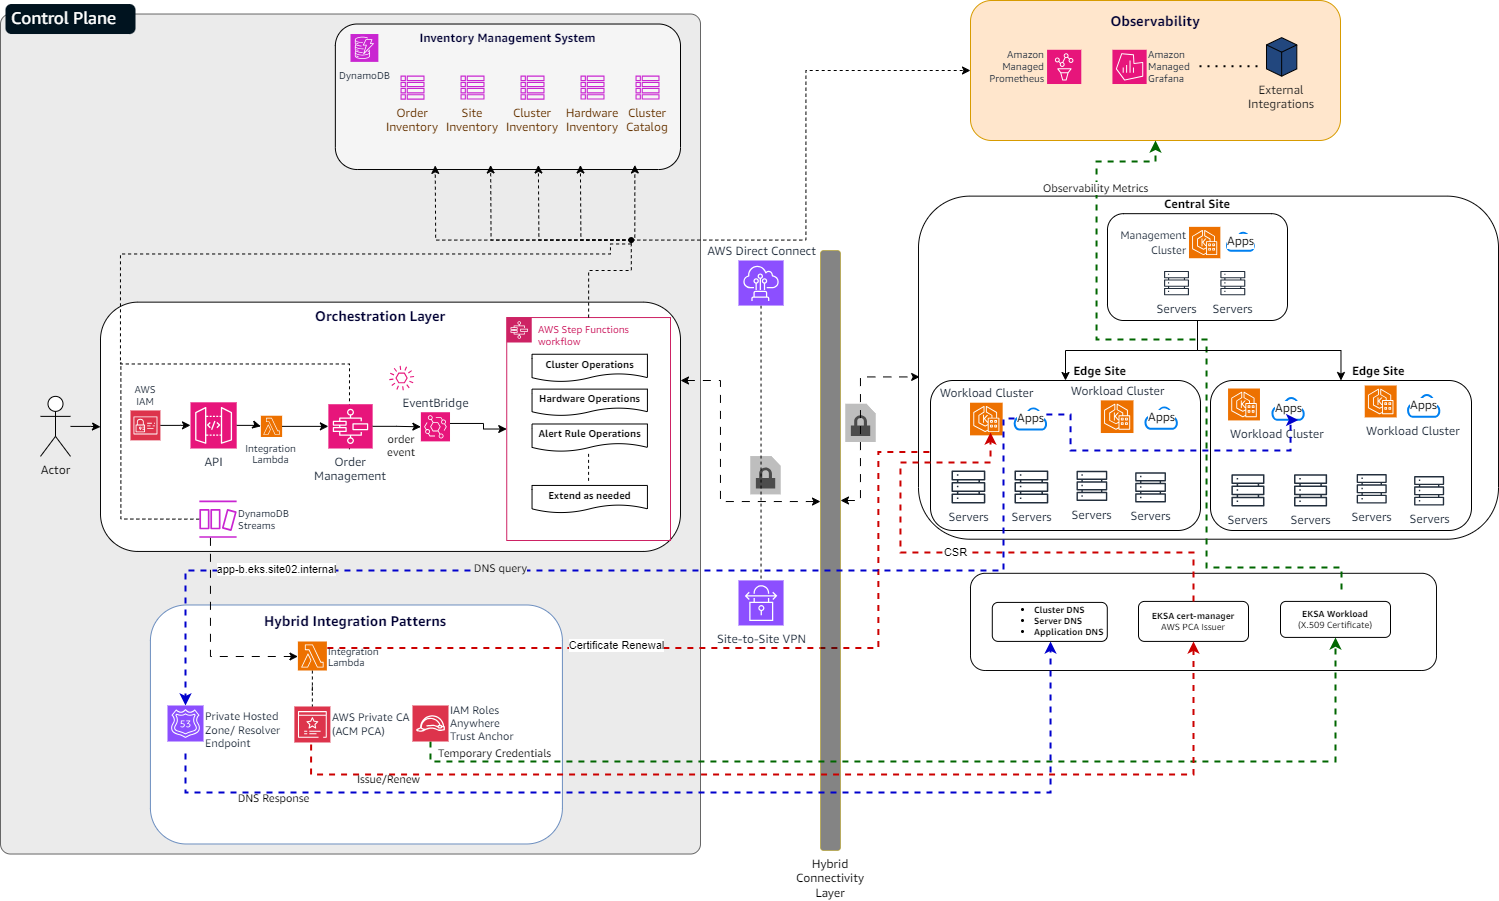
Figure 1: High-level architecture of the hybrid cloud orchestration solution
The architecture consists of three primary layers: a centralized orchestration engine on AWS, distributed on-premises infrastructure running EKS Anywhere clusters, and hybrid connectivity linking the two environments. Serverless technologies coordinate lifecycle operations across hundreds of sites while maintaining comprehensive state tracking through an Inventory Management System.
Foundational concepts
The architecture is built on several foundational concepts that organize how resources are managed, and operations are coordinated.
Site: A physical location or logical grouping housing on-premises infrastructure. Sites provide an organizational framework for distributed operations, supporting location-specific policies, connectivity requirements, and compliance controls (for example, central, regional, or edge data centers).
Server: Bare-metal servers within sites that provide the physical compute, storage, and networking foundation for containerized workloads. Hardware resources are managed through vendor-agnostic Redfish APIs.
Cluster: EKS Anywhere Kubernetes clusters deployed on hardware resources, consisting of both management clusters (for orchestration operations) and workload clusters (for hosting applications).
Order: A trackable infrastructure lifecycle operation that executes as a workflow. When an operator requests an action like rebooting all servers in a site, an order is created with a unique ID. This emits an event, which Amazon EventBridge routes to the corresponding AWS Step Functions workflow. Operators can monitor progress by checking the order status, which is updated in response to state-change events emitted by the running workflow.
Inventory Management System: Centralized state repository
The Inventory Management System is the central state repository, using DynamoDB tables to track infrastructure resources and their relationships across hundreds of distributed sites.
DynamoDB tables maintain information about sites, hardware, clusters, orders, and a catalog of reusable configurations. Sites organize resources by location, storing network configurations, gateway addresses, and regional information. Hardware inventory captures server configurations (BIOS and firmware versions, encrypted credentials), network details (IP addresses, MAC addresses), operational status, physical location (rack number, mounting position), and cluster membership. Clusters maintain Kubernetes configurations, node group details, addon versions, and relationships to management clusters. Orders track operation lifecycles from initiation through completion, capturing the operation type, target resources, execution status, and workflow outputs. The catalog stores vetted blueprints and templates that standardize deployments across the infrastructure.
As infrastructure changes occur, the inventory reflects the current state of resources and their dependencies, acting as the single source of truth for operational history and resource relationships.
Event-driven orchestration engine
With centralized state tracking using the Inventory Management System, the orchestration engine coordinates infrastructure operations through an API-driven framework built on AWS serverless technologies. This architecture delivers scalable, event-driven orchestration without operational overhead.
API layer
The API layer exposes a RESTful interface through Amazon API Gateway for create, read, update, and delete (CRUD) operations on infrastructure resources. A unified operator portal serves as the front end for this API, giving operators a self-service interface to perform lifecycle operations without requiring CLI or direct API knowledge. Lambda functions process incoming requests, validate parameters, and integrate with the order management system to initiate operations.
Orchestration layer
Step Functions executes specialized state machines that integrate with AWS services for compute, storage, and networking operations, providing retry logic, error handling, and state checkpointing.
Step Functions supports a callback pattern where a workflow can pause, hand off a task to an external system with a unique token and resume only when that system calls back with the token. This is critical for hybrid cloud orchestration because it allows workflows to pause execution and wait for external systems to signal completion. This capability addresses the challenge of coordinating AWS-based workflows with on-premises systems that may take hours to complete operations like firmware updates or cluster deployments. A workflow can hand off a task to on-premises infrastructure, pause, and resume only when the on-premises system reports back.
The Distributed Map state scales operations from individual resources to thousands across multiple sites. For example, a workflow that manages the power state of a single server can scale to manage power states across thousands of servers simultaneously.
Amazon EventBridge provides event-driven automation capabilities, triggering workflows based on infrastructure state changes. When inventory records are updated, Amazon EventBridge Rules evaluate the changes and invoke appropriate Step Functions workflows. This decouples components and supports reactive automation patterns, such as automatically scaling clusters when capacity thresholds are reached or starting maintenance workflows when hardware health checks fail.
Security and configuration
Security and configuration management are handled through multiple AWS services. AWS Systems Manager Parameter Store provides centralized configuration storage, while AWS Secrets Manager securely manages sensitive credentials and secrets. AWS Identity and Access Management (IAM) roles provide fine-grained access control across components, with IAM Roles Anywhere extending AWS access to on-premises clusters without requiring long-term credentials.
AWS Systems Manager hybrid activations register on-premises instances with AWS, allowing the Systems Manager agent to manage on-premises infrastructure alongside cloud resources. This delivers a unified management interface for configuration, patching, and command execution across both environments.
AWS Private Certificate Authority manages certificates for secure communications between orchestration components and on-premises infrastructure. Each component operates with least-privilege permissions, accessing only the resources required for its specific function.
Order management: Coordinating operations at scale
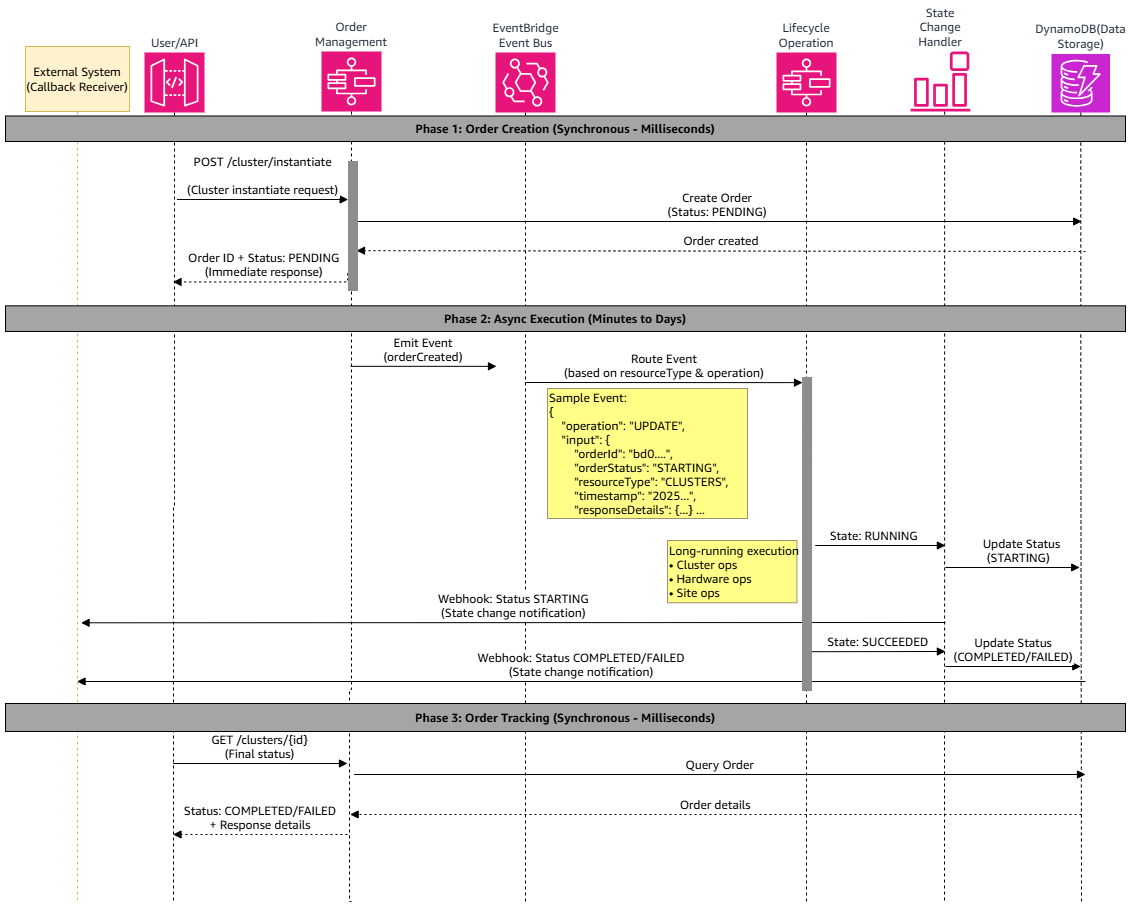
Figure 2: Order management flow from API request to workflow execution
The orchestration engine coordinates operations through an order management system built on Amazon EventBridge rules that map API operations to Step Functions workflows. When an API request initiates an operation like `/clusters/{id}/terminate`, an Amazon EventBridge Rule routes the request to the corresponding workflow based on the resource and operation type. The system creates a record in DynamoDB and returns an order ID immediately, while the workflow executes asynchronously.
This event-driven system listens and responds to events throughout the operation lifecycle. As workflows execute, AWS-managed events from Step Functions and custom events from workflow logic progressively update the order status in DynamoDB. This allows operators to initiate operations without waiting for completion, which may take minutes to hours depending on the complexity of the operation.
The following core capabilities are enabled by order management:
Order lifecycle tracking: Operators can query order status through the API to monitor progress and track the complete audit trail from creation through execution to completion or failure.
Callback support: Orders support callbacks to both other workflows and external webhooks. Workflows can trigger other workflows upon completion, while webhook endpoints receive notifications upon state changes or completion. This supports integration with external systems such as ticketing platforms, notification services, or custom dashboards.
Conflict management: Integration with the inventory system prevents conflicting operations by denying new orders if another one is running on the same resource, preventing scenarios like cluster scaling during an upgrade.
Extensibility: New resource types and operations can be added by implementing Step Functions workflows and registering Amazon EventBridge rules that map API endpoints to workflows. The core order tracking logic remains unchanged.
Lifecycle management framework
The lifecycle management framework addresses two primary resource types, each with distinct operational requirements: bare-metal hardware and Kubernetes clusters.
Hardware management
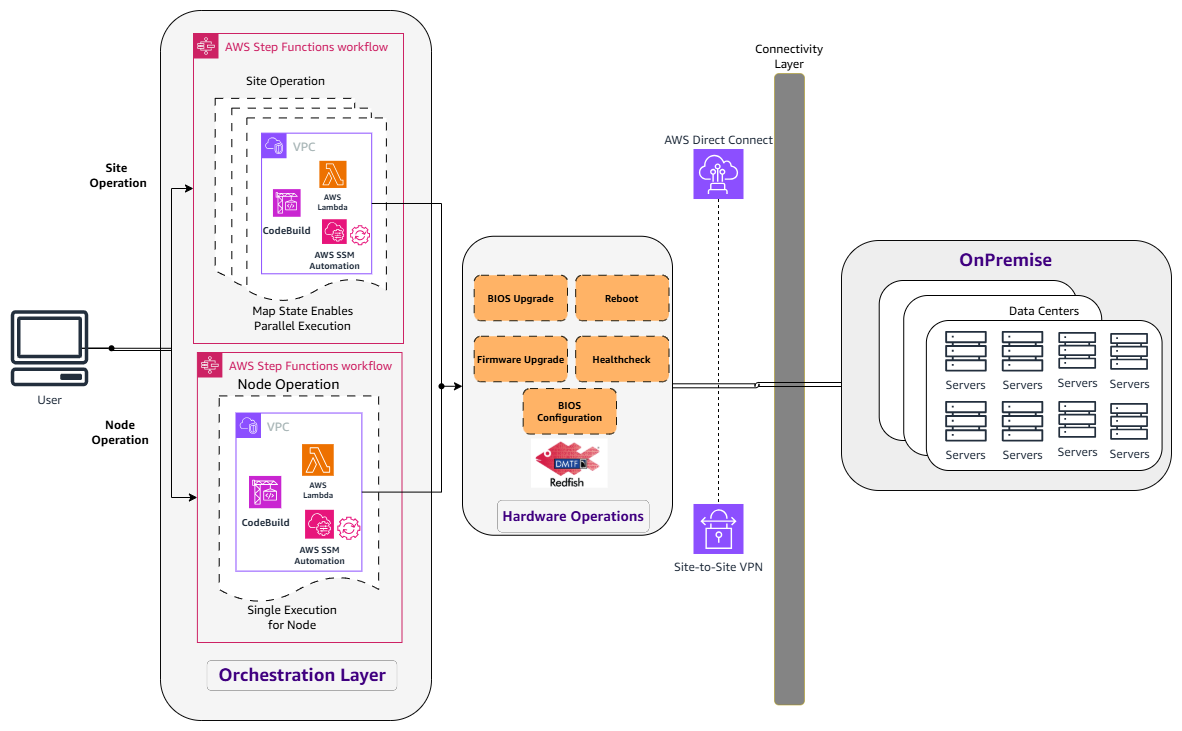
Figure 3: Hardware lifecycle management across distributed sites
The solution provides hardware lifecycle management across distributed on-premises sites through a vendor-agnostic approach integrated with the Inventory Management System.
Supported hardware lifecycle operations
- Firmware management: Automated updates and configuration management.
- NIC upgrades: Network interface card firmware updates.
- Power management: Remote reboot, shutdown, and power cycling.
- Health: Processor, memory, and disk health checks.
- BIOS configuration: Define and apply specific golden templates.
This approach automates traditional manual hardware management, so operations can efficiently handle hundreds of servers across multiple distributed sites.
Cluster management
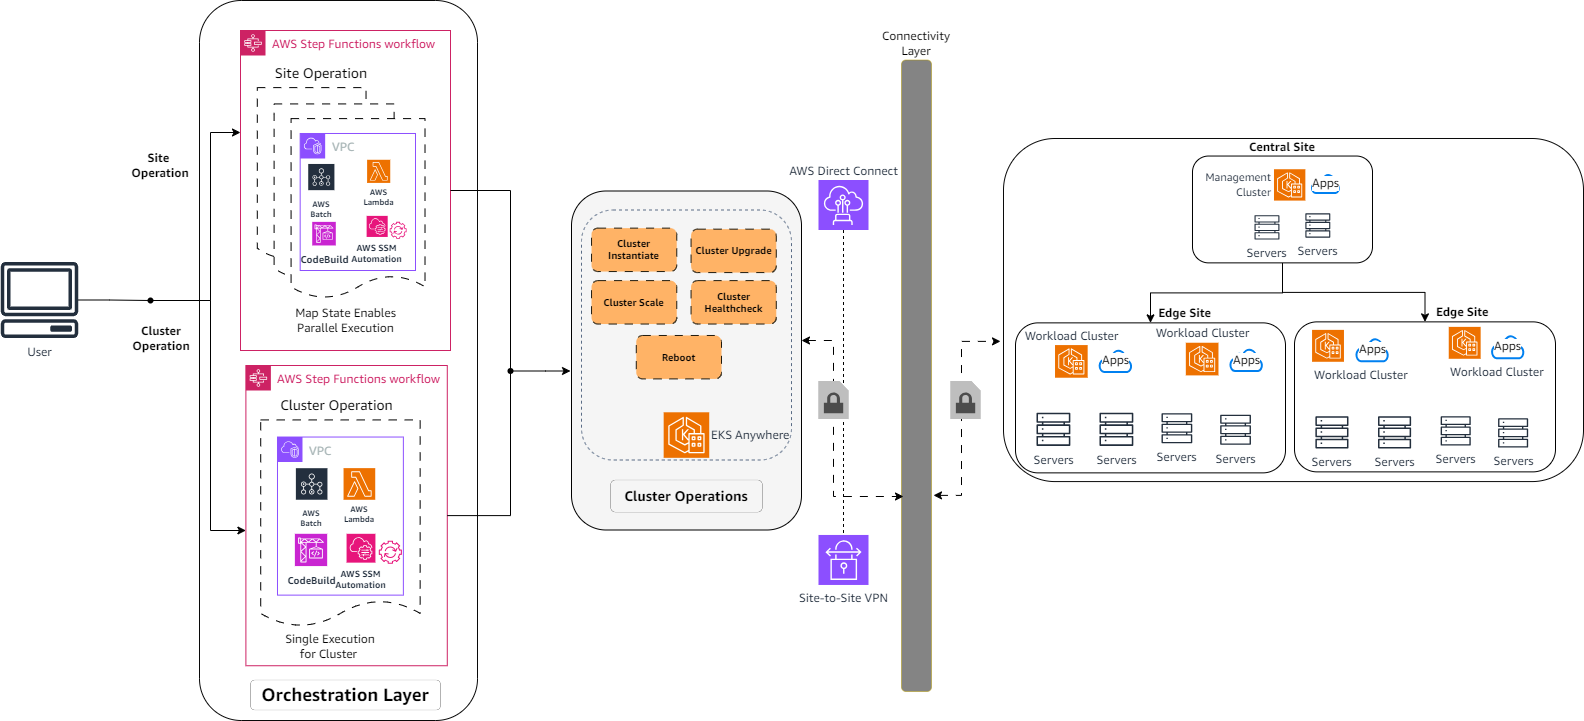
Figure 4: EKS Anywhere cluster lifecycle management across sites
Cluster management uses Amazon EKS Anywhere for consistent Kubernetes operations across sites. To create a cluster from bare metal servers, a configuration file and a hardware inventory CSV that lists the servers and their network details are prepared and passed to the EKS Anywhere CLI, which network boots them, installs the operating system and Kubernetes, and brings up the cluster. For the full set of steps and configuration options, see the EKS Anywhere bare metal documentation.
EKS Anywhere supports two cluster types:
- Management: Dedicated clusters that host orchestration components to manage the lifecycle of workload clusters.
- Workload: Application-hosting clusters managed by their corresponding management cluster.
This mapping of management to workload clusters is maintained in the Inventory Management System to give a unified view of cluster distribution across the infrastructure. When an operator requests a cluster through the API, the orchestration engine assembles the required inputs: the configuration file comes from a blueprint in the Cluster Catalog, and the hardware CSV comes from the servers recorded in the Inventory Management System. A workflow then runs the EKS Anywhere commands through Systems Manager (SSM) and Batch, which execute them against the on-premises servers.
Scalable operations
Cluster operations must execute in the proper sequence across the distributed environment, handling dependencies between clusters and their components. For instance, cluster creation begins with hardware selection based on placement strategy, pre-flight checks, bootstrapping an Admin machine, executing on-premises commands and awaiting completion, add-ons installation, and post-deployment health checks. The orchestration engine handles this using Step Functions with child workflows, callback patterns, and dependency mapping.
Supported cluster lifecycle operations
- Cluster creation: Automated provisioning of management and workload clusters with customizable configurations.
- Cluster scaling: Dynamic addition or removal of worker nodes based on capacity requirements.
- Cluster upgrades: Coordinated Kubernetes version upgrades with minimal disruption.
- Cluster termination: Graceful cluster decommissioning with proper resource cleanup.
These automated workflows reduce the operational complexity of managing Kubernetes at scale and support consistent cluster operations from edge locations to central data centers.
Monitoring and observability
Managing geographically distributed infrastructure requires centralized observability since operators often need to investigate issues across individual sites, correlating data from different hardware vendors and software layers.
This solution addresses the fragmented visibility challenge by aggregating telemetry from on-premises clusters into managed AWS services. AWS Distro for OpenTelemetry (ADOT), deployed as a collector on each EKS Anywhere cluster, scrapes and forwards metrics from the server, Kubernetes, and application layers to Amazon Managed Service for Prometheus in the AWS Region. Amazon Managed Grafana then provides unified dashboards and alerting across the entire distributed environment.
With this approach, operators can monitor server availability (through Redfish events or Prometheus node-exporter), Kubernetes cluster health (through kube-state-metrics), and application-level metrics from one place, regardless of the underlying hardware vendor.
For a detailed implementation walkthrough, including Redfish event subscription patterns, OpenTelemetry collector configuration, Prometheus alerting rules, and Grafana dashboard setup for distributed sites on EKS Anywhere, see our related post: Building observability on Amazon Managed Grafana built on EKS Anywhere.
Hybrid integration patterns
Although EKS Anywhere clusters run on-premises, applications on them can depend on capabilities that span the cloud boundary: DNS resolution across both environments, TLS certificates, access to AWS APIs, and persistent storage. AWS offers services designed for this hybrid integration, and the orchestration engine can apply them automatically from its inventory as clusters and applications change.
Automated DNS management
When the state of a cluster, server, or application changes, Amazon DynamoDB Streams automatically trigger Lambda functions that update DNS records in Amazon Route 53 private hosted zones. Route 53 Resolver endpoints make these records resolvable from both AWS and on-premises, which supports service discovery without manual DNS configuration.
Certificate lifecycle operations
AWS Private Certificate Authority acts as a managed CA for the clusters, so there is no need to run a certificate authority at each site. cert-manager and the AWS Private CA Issuer request, renew, and distribute certificates from it automatically, which helps avoid outages from expired certificates.
Secure AWS access
Workloads on the clusters often need to call AWS APIs, such as sending Fluent Bit logs to Amazon Simple Storage Service (Amazon S3), publishing metrics to Amazon Managed Service for Prometheus, or pulling images from Amazon Elastic Container Registry (Amazon ECR). AWS IAM Roles Anywhere issues short-lived AWS credentials in exchange for a certificate the workload already holds, so no long-lived keys are stored at each site. It accepts that certificate only if it chains to a trusted source, so the orchestration engine registers each cluster’s own CA certificate as its trust anchor when the cluster comes up.
Persistent storage integration
External storage solutions such as Portworx can be integrated for stateful applications. DynamoDB Streams trigger automated interactions with storage provider APIs during node provisioning and cleanup operations and perform the configuration and reclaiming of storage resources.
The event-driven approach makes it possible for dependent infrastructure components to remain synchronized with the actual state of clusters and hardware, reducing operational overhead and minimizing configuration drift.
Conclusion
This blog post explores the architecture and capabilities of the hybrid cloud orchestration solution that modernizes on-premises infrastructure management using AWS technologies and EKS Anywhere. We’ve demonstrated how you can build a scalable, event-driven orchestration engine that manages your distributed infrastructure across hundreds of sites while maintaining operational consistency.
What’s next
In this post series, we’ve focused on the architectural patterns and capabilities that enable enterprise-scale hybrid cloud orchestration. To get started today, review the Amazon EKS Anywhere documentation and set up a bare-metal cluster or use the Docker provider for development and testing. In Part 2, we walk through the implementation of the orchestration solution with infrastructure-as-code templates, Step Functions workflow definitions, and operational runbooks you can adapt to your environment. Follow the AWS Containers blog for the next installment.
About the authors
Security updates for Tuesday
Post Syndicated from jzb original https://lwn.net/Articles/1091919/
Security updates have been issued by AlmaLinux (gzip, iperf3, libxml2, mingw-sqlite, mysql:8.4, nginx:1.26, nodejs:24, php, and tar), Debian (expat and libdbd-csv-perl), Fedora (apache-ivy, bind, bluez, bubblewrap, curl, emacs, epiphany, expat, freerdp, gdk-pixbuf2, GitPython, hcloud, kbd, kernel, lego, libopenmpt, mqttcli, nebula, opkssh, python-mkdocs-git-revision-date-localized-plugin, python-pip, rpki-client, rubygem-mechanize, srt, and subfinder), Mageia (c-ares, clamav, expat, mingq-expat, firefox, nspr, nss, flatpak, hplip, jbig2dec, nodejs, openssl, perl-Catalyst-Plugin-Authentication, perl-Date-Manip, perl-HTML-FormHandler, perl-HTTP-Date, perl-Mojolicious, perl-Plack, postgresql15, postgresql18, python-hpack, redis, roundcubemail, thunderbird, varnish, and vim), Oracle (golang and libxml2), Red Hat (bind, bind9.18, dracut, glib2, golang, gzip, kernel, kernel-rt, openssl, osbuild-composer, tar, and unbound), SUSE (7zip, busybox, bzip2, c-ares, chromedriver, chromium, cpio, curl, dhcpcd, dovecot24, dracut, firefox, go1.25, go1.26, go1.26-openssl, google-cloud-sap-agent, gstreamer-plugins-bad, gzip, helm, ImageMagick, istioctl, jfrog-cli, jupyter-jupyterlab, libarchive, libcares2, libheif, liboqs, librest, openssl-1_1, openssl-3, owasp-modsecurity-crs, pcp, php-composer2, postgresql14, postgresql15, postgresql17, postgresql18, python-cryptography, python-httplib2, python-pip, python313, python313-djangorestframework, python313-starlette, qemu, qt6-svg, quagga, rav1e, rmt-server, rsync, rsyslog, snphost, sssd, thunderbird, unbound, vim, wget, xmlrpc-c, yast2-auth-client, and yast2-samba-client), and Ubuntu (attr, bind9, coreutils, cpio, diffutils, freerdp3, libssh, mysql-8.0, mysql-8.4, openjdk-17-crac, openjdk-21-crac, openjdk-25-crac, openssl, p11-kit, perl, pillow, udisks2, util-linux, webkit2gtk, zfs-linux, and zlib).
MCP went stateless: Is your AWS MCP server deployment well-architected?
Post Syndicated from Anand Komandooru original https://aws.amazon.com/blogs/architecture/mcp-went-stateless-is-your-aws-mcp-server-deployment-well-architected/
On July 28, 2026, MCP published its largest revision since launch, making the protocol core stateless and bringing remote MCP servers into alignment with AWS Well-Architected Framework best practices. The initialize handshake is gone, and so is the Mcp-Session-Id header that clients had to echo on every later request. Every request now carries its own protocol version and client context. A client’s first message can be the actual tool call, and any server instance can respond to it. If your MCP server was built for the session-based protocol, the sticky sessions, shared session stores, and custom observability plumbing it required are no longer necessary. If you run behind Amazon Bedrock AgentCore Gateway, protocol management and backward compatibility are handled for you. This post is for teams managing the full deployment stack themselves.
If a client wants to know what a server supports before calling it, a new server/discover method returns the supported protocol versions, capabilities, and identity in a single response. Servers must implement it per the MCP 2026-07-28 specification, but calling it is optional for the client.
This matters on AWS because the old design fought horizontal scaling. A session lived on whichever instance issued it. Running more than one instance meant either pinning clients with sticky routing or externalizing session state to a shared store. Both were correct for that protocol. With the new protocol, neither is required. This post maps the MCP 2026-07-28 specification against the Well-Architected Agentic AI Lens and recommends migrating, because the new protocol achieves natively what the old one could only achieve through compensating infrastructure.
One thing to settle up front, because it drives everything else: stateless describes the protocol, not your application. Stateful use cases still work.
Think of it as a coat check. Under the old protocol the server was a valet who remembered your face, which meant you had to keep dealing with that same valet and nobody else could help you. Now you get a numbered ticket, and any attendant can serve you because the ticket carries the reference. When a server needs continuity across calls, a tool returns an identifier for the stored state. The model includes that identifier on the calls that follow. The state stays in your datastore. The model carries only the key. This is ordinary REST discipline. It has an advantage over the old model. The identifier sits in the model’s context rather than hidden in a header. The model can reason about it and thread it across tools.
What changes in your architecture
The following table compares the deployment patterns the session-based protocol required against the patterns the stateless core now supports.
| Before (session-based) | After (2026-07-28 stateless) |
| Elastic Load Balancing Application Load Balancer (ALB) stickiness so each session reaches the same instance. | Plain round-robin. Delete the stickiness configuration. |
| Session state in Amazon DynamoDB or Amazon ElastiCache. | No session store. Server-minted identifiers passed as tool arguments. |
| Parse request bodies at the gateway to route by method. | Route and throttle on the Mcp-Method and Mcp-Name headers. |
| AWS Lambda required workarounds for the stateful handshake. | AWS Lambda is a natural fit. Request in, response out. |
| Refetch tool lists per session. No caching story. | Cache with ttlMs and cacheScope, the protocol’s built-in freshness fields. |
| Bolt-on tracing per implementation. Proprietary protocol logging channel. | W3C Trace Context in _meta for distributed tracing. stderr or OpenTelemetry for logging. Protocol logging is deprecated. |
Rely on stream resumption (Last-Event-ID) for broken responses. |
Make tools idempotent. Clients re-issue broken calls. |
 Don’t delete yet if you serve 2025-era clients. The 2026-07-28 spec includes a backward-compatible lane that preserves session semantics for older clients. Your ALB stickiness rules and session store (DynamoDB/ElastiCache) must remain in place until you stop serving pre-2026-07-28 clients.
Action: Instrument your gateway to log protocol version per request. Set a sunset date for the legacy lane and communicate it to client teams. Only decommission session infrastructure after traffic on the old version reaches zero. This guidance applies to session infrastructure built to compensate for the old protocol’s requirements. Managed hosts that offer session features by design for specific use cases are not in scope.
One behavioral change to plan for. Servers can no longer push a request to a client mid-call, which is how confirmations, sampling, and root queries used to work over a held-open stream. The spec replaces that pattern with Multi Round-Trip Requests (MRTR). A server that needs input returns an input_required result containing an inputRequests map. This map holds elicitations, sampling calls, or root queries, and an opaque requestState token. The client fulfills the requests, then re-sends the original call with inputResponses and the echoed requestState. Any instance can pick that up because requestState carries all the context the server needs to resume. No shared session store is required. The server does not hold the connection open. This is what makes the pattern work on AWS Lambda.
The Well-Architected view
The AWS Well-Architected Agentic AI Lens already prescribes standardized protocol-based integration as a best practice. For more detail, refer to Establish standardized tool integration protocols (MCP, A2A). What follows is not new guidance but a reading of how the MCP 2026-07-28 specification makes those best practices genuinely achievable for a remote MCP server, pillar by pillar.
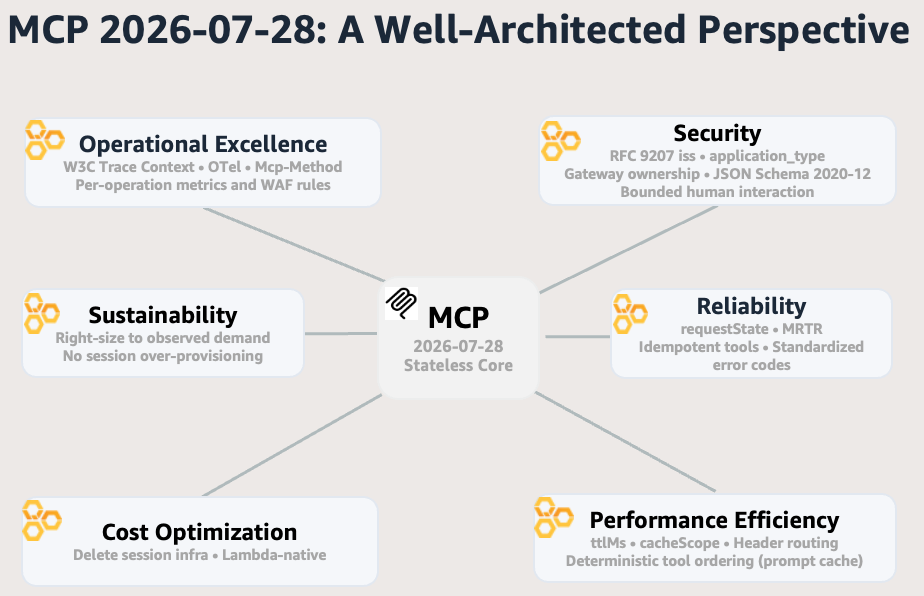
Figure 1: How the MCP 2026-07-28 specification maps to the Well-Architected Agentic AI Lens pillars
Operational excellence. The Lens identifies observability as the foundation for operating agents. If you cannot trace a decision end to end, you cannot debug, optimize, or audit it. The 2026-07-28 spec builds observability into the protocol itself. Three changes make this concrete:
- Tracing. Every request carries W3C Trace Context keys in _meta (
traceparent,tracestate,baggage), so it traces end to end through any OpenTelemetry-compatible backend, including Amazon CloudWatch. The Lens prescribes end-to-end tracing and telemetry for agent operations. - Operational signals without body parsing. The Mcp-Method and Mcp-Name headers expose the operation type on every POST, and every response carries a required resultType field (
completeorinput_required). Gateways and observability tools get unambiguous per-operation signals for metrics, alarms, and AWS WAF rules without inspecting payloads. The result directly addresses the Lens recommendation for implementing metrics and monitoring for agent-specific patterns. - Standardized logging. MCP’s proprietary protocol logging is deprecated in favor of
stderrand OpenTelemetry. The Lens makes the same recommendation: implement structured logging through standardized, queryable formats.
Security. The Lens treats agent security as harder than traditional service security: agents act autonomously with delegated credentials, and their inputs (including state identifiers) are visible to, and potentially manipulable by, the model. MCP’s 2026-07-28 spec hardens the protocol surface against these risks. Five changes strengthen the security posture:
- Issuer validation. Clients must validate the iss parameter per RFC 9207, confirming which authorization server produced a response. The Lens calls for the same discipline under strong authentication for agent identities.
- Client type declaration. Clients must declare application_type at registration so a desktop or CLI client is not mistaken for a web app, verifying authentication mechanisms match the client’s security profile. The same Lens best practice applies: strong authentication for agent identities. (Note: Dynamic Client Registration itself is now deprecated in favor of Client ID Metadata Documents.)
- Bounded human interaction. A server can prompt a user only while it is handling that user’s request, through the Multi Round-Trip Requests pattern. This is a protocol-enforced constraint that bounds when human interaction can occur, aligning with the Lens’s human-in-the-loop controls for critical decisions.
- Ownership enforcement. Because state identifiers are visible to the model, servers must enforce ownership on every call. The protocol will not stop a caller from presenting an identifier that is not theirs, so the Lens best practice for tool authorization at the gateway applies: validate that the requesting identity owns the resource it references. The same discipline applies to requestState tokens: the spec requires servers to treat them as untrusted input and protect their integrity with HMAC or AEAD, rejecting any token that fails verification.
- Schema validation. Tool input and output schemas are now validated against JSON Schema 2020-12, giving servers a formal contract for rejecting malformed or injected arguments before execution. This maps to the Lens requirement to validating tool inputs at the boundary.
Reliability. Agents hold multi-step context that is expensive to reconstruct after failure, making reliability harder than in traditional services. MCP’s 2026-07-28 spec addresses this at the protocol layer. Four changes reduce that fragility:
- Stateless transport. The spec removes protocol-level sessions, so any instance can serve any request. Instance loss is a non-event. Retries need no session affinity, and scale-in never drains sessions. The protocol embodies the failure-isolation philosophy at the protocol layer without additional infrastructure.
- Continuation tokens. Interrupted multi-step interactions resume through requestState, an opaque continuation token the server returns and the client echoes on retry. This embodies the Lens principle of designing workflows in stages with incremental recovery.
- Idempotent retry. Stream resumability was removed, so a broken response stream loses the in-flight payload and the client must re-issue the call. The mitigation is the same idempotent task execution pattern the Lens prescribes for retryable agent actions: make tools idempotent so re-issued requests produce no duplicate side effects.
- Standardized error codes. The spec allocates error code ranges (-32000 to -32019 implementation-defined, -32020 to -32099 reserved for MCP), giving clients and gateways a canonical signal set for retry, backoff, and circuit-breaking decisions. Gateways can now implement standardized communication protocols.
Performance efficiency. Redundant data fetches and per-interaction protocol overhead are the two main performance drags the Lens identifies in agentic workloads. MCP’s 2026-07-28 spec addresses both at the protocol layer. Three changes reduce that overhead:
- Protocol-declared caching. Two fields are now required on list and resource-read results:
ttlMs(how many milliseconds a response stays fresh) andcacheScope(whether shared intermediaries can cache it or only the requesting client). Tool lists now return in deterministic order, allowing LLM prompt-cache hits across calls. The protocol now delivers what the Lens recommends under optimizing inference-time performance for agent workloads. - Freshness semantics. Clients and MCP-aware gateways can cache responses using protocol-declared freshness (
ttlMs+cacheScope), the same data-type-specific TTL discipline the Lens recommends under protocol-declared freshness semantics, without guessing at staleness. - Header-based routing. Routing and throttling decisions now live in HTTP headers (
Mcp-Method,Mcp-Name) rather than parsed message bodies, reducing per-interaction overhead in line with what the Lens prescribes for efficient protocol-based agent communications.
Cost optimization. The Lens identifies always-on infrastructure serving bursty agent traffic as the highest source of idle cost in an agent stack. MCP’s stateless architecture eliminates an entire category of that cost: session infrastructure.
- Delete session infrastructure. Audit for anything that exists only to preserve sessions (ElastiCache clusters, sticky-routing rules, session-replication logic) and delete it. This follows the same principle the Lens applies to cost-optimizing tool serving through serverless and resource sharing. Infrastructure that runs constantly to serve unpredictable traffic should be replaced with consumption-based patterns that scale to zero. A two-node Amazon ElastiCache (cache.t4g.micro) session store is about $23/month (AWS Pricing Calculator, July 2026). The larger saving is eliminating an entire class of infrastructure and the operational burden around it. Sticky routing costs capacity too by distributing load unevenly, and the savings scale with the size of your fleet.
- Serverless as first-class pattern. AWS Lambda has no sticky routing and no persistent connections. A session-based MCP server meant externalizing state to a shared store. Even a “session-free” mode still paid for the mandatory handshake. With the 2026-07-28 stateless core, request in, response out is exactly what AWS Lambda does natively. Serverless MCP moves from workaround to first-class pattern, delivering what the Lens recommends for cost-optimizing tool serving through serverless and resource sharing.
Sustainability. The Lens identifies static provisioning for bursty agent traffic as the primary source of wasted infrastructure capacity. The 2026-07-28 spec’s stateless architecture eliminates the structural reasons for that over-provisioning.
- No more pinned-session capacity. The spec’s stateless design means no instance holds a session, so no instance needs to stay warm for one. Right-size against your actual traffic pattern rather than a theoretical peak, the same principle the Lens applies to appropriately scaling compute, networking, and data dependencies for agent workloads. Instance-agnostic routing means the fleet you do keep can run closer to its real utilization, instead of padding for the instances that happened to hold long-lived sessions.
The AWS Well-Architected Agentic AI Lens articulated these best practices as general principles for agentic workloads. The fact that a major protocol revision, designed independently, converges on the same architectural shape is evidence that the framework captures something real about how reliable distributed systems need to work.
What to watch
The architectural shift creates its own operational surface. These are the areas where the new defaults need deliberate attention rather than passive adoption.
Long-lived streams did not disappear. The subscriptions/listen method consolidates change notifications into a single opt-in POST-response stream, so check idle timeouts across your load balancer, proxy, and compute tier if your servers use it.
Deprecations with a clock. The spec deprecated Roots, Sampling, Logging, and the HTTP+SSE transport with a twelve-month floor before removal. The earliest any of these can be removed is July 2027. It also removed ping, logging/setLevel, and notifications/roots/list_changed outright, and moved log level into per-request _meta. The suggested migration paths:
- Pass directories through tool parameters or resource URIs instead of Roots.
- Integrate directly with LLM provider APIs instead of Sampling.
- Log to
stderror OpenTelemetry instead of protocol-level Logging. - Migrate HTTP+SSE to Streamable HTTP.
Plan the exits now rather than at the deadline.
MCP Apps puts server-supplied HTML inside your host. Pre-declared UI resource templates, mandatory iframe sandboxing, and auditable JSON-RPC communication between the iframe and host all help. But treat template review as mandatory before deployment, and decide deliberately which servers in your fleet can ship UI at all.
cacheScope is a multi-tenant disclosure risk. Setting cacheScope: "public" on a response that contains tenant-specific data lets shared intermediaries serve one tenant’s list to another. Default to "private" and widen deliberately only for responses that are genuinely identical across callers.
Built-in protection against future breaks
Three mechanisms shipped alongside the stateless core to prevent a repeat of this kind of breaking change.
A feature lifecycle policy gives every feature an Active, Deprecated, or Removed state. Nothing can be removed until at least twelve months after it is deprecated. An extensions framework lets new capabilities ship as opt-in extensions that prove themselves outside the core. That is where Tasks landed after its experimental version needed a redesign. And no Standards Track proposal can reach Final status without a matching scenario in the conformance suite. This is the same suite the official SDKs are validated against.
The handshake and session removal were a deliberate, one-time break to fix the foundation. From here, what you build against 2026-07-28 comes with documented notice periods.
Self-check
Run these ten questions against your own deployment before you decide whether, and how, to migrate.
- Can any instance of your server handle any request, with no session affinity at the load balancer?
- Have you deleted everything that existed only to preserve a protocol session?
- Do your list responses set
ttlMsandcacheScopedeliberately, and does your gateway route on headers rather than parsed bodies? - Does every client validate
iss, and does every server enforce ownership per identifier rather than trusting the identifier itself? - Do you have a firm date to stop supporting 2025-11-25 clients?
- Have you replaced server-initiated pushes with Multi Round-Trip Requests so no instance holds a connection open for client input?
- Are your tools idempotent so clients can safely re-issue any broken call?
- Do you propagate W3C Trace Context end-to-end and emit logs through
stderror OpenTelemetry instead of MCP protocol logging? - Are you still paying for session infrastructure (DynamoDB, ElastiCache, sticky routing) that nothing uses?
- Do you have a governance policy for MCP Apps before any server in your fleet exposes one?
A “no” to any of these is where the new spec pays off. Each maps to the pillar sections earlier in this post. Start with the migration path that follows, run your server against the official conformance suite, and use the related AWS resources at the end to plan the change.
Migration path
You do not need to move immediately. Protocol versions are frozen snapshots, and a client and server only need to share one, so 2025-11-25 servers keep working with clients that still speak it. But hosts retire old versions on their own timeline, the community is already moving (GitHub’s MCP Server shipped support ahead of the release), and 2025-11-25 is now frozen. Future capabilities and fixes land on 2026-07-28 or later.
For a new server, target 2026-07-28 directly: stateless from the start, explicit identifiers, and no dependence on Roots, Sampling, or MCP Logging.
For an existing server, work through these steps in order:
- Upgrade the SDK and opt in. Speaking the new revision is never automatic.
- Audit for session assumptions and migrate off the experimental Tasks API if you used it (Tasks is now an official extension with a redesigned interface).
- Plan the deprecation exits (Roots, Sampling, Logging, HTTP+SSE) and change the resource-not-found error code from
-32002to-32602. - Collect the infrastructure savings by deleting session stores, sticky-routing rules, and handshake infrastructure.
For a platform or gateway team: add header-based routing and per-operation throttling on Mcp-Method, honor ttlMs and cacheScope in your caching layer. Also propagate W3C Trace Context, and set a policy for MCP Apps before the first server in your fleet ships one.
Validate before you ship. The official conformance suite covers the new behaviors, and protocol inspectors can pin 2026-07-28 to test your server against exactly what clients will send. Start in a test environment, then promote to production once the suite passes.
Conclusion
The session-based protocol was correct for the constraints it operated under, but those constraints are gone. If you are deploying MCP servers on AWS, the 2026-07-28 specification is the Well-Architected path forward. Migrate your servers, sunset your legacy lane, and delete the infrastructure that existed only to compensate for a protocol limitation that no longer applies.
About the authors
Scheduling email campaigns at scale with Amazon EventBridge Scheduler
Post Syndicated from Oluwaseun Ademuwagun original https://aws.amazon.com/blogs/compute/scheduling-email-campaigns-at-scale-with-amazon-eventbridge-scheduler/
Scheduling email campaigns becomes more complex when you need to send email to millions of recipients at the unique time best suited for each customer. Consider these examples:
- A flash sale might need to hit inboxes at 9 AM local time across every time zone.
- A follow-up email (often known as a drip sequence) might need to send a second message exactly 3 days after the first message per subscriber.
- A re-engagement campaign might target users who haven’t logged in for 30 days.
The scheduling requirements involve multiple considerations. You’re sending hundreds of millions of messages, each at its own optimal moment personalized to the recipient’s time zone and behavior.
In this post, we walk through how to use Amazon EventBridge Scheduler to personalize email notifications to each recipient. We create one schedule per recipient to deliver each email at its individually optimal moment, with zero idle compute cost. We also show how Amazon EventBridge Scheduler handles higher volumes. Amazon EventBridge Scheduler supports billions of schedules. By default, you have a quota of 10 million schedules.
Solution overview
When every recipient has their own ideal delivery time, you need a scheduling layer that can hold billions of individual send intents and fire each one at the right moment. Most teams reach for one of three familiar patterns, each with tradeoffs that become painful at scale.
- Batch cron jobs: A job runs every hour, queries for all messages due in the next window, and sends them out. Recipients get email in imprecise hourly batches. At scale, the batch job itself becomes a bottleneck, processing millions of rows per run, competing for database connections, and creating a sudden spike in load on the email provider.
- Delay queues: You can use Amazon Simple Queue Service (Amazon SQS) as a delay queue. A delay queue postpones the delivery of new messages to a customer for a set time. A limitation of this approach is that Amazon SQS caps delays at 15 minutes.
- Third-party campaign tools: Offload to a SaaS email platform. This works until you need tight integration with your application data, custom send-time optimization, or control over delivery infrastructure. You’re also paying per-recipient fees that compound at scale.
All three approaches either sacrifice precision (batching), hit architectural limits (delay queues), or surrender control (third-party tools).
The building block approach
Amazon EventBridge Scheduler treats each email send as a discrete scheduled action. Instead of “process all messages due this hour,” you express the intent directly: “send this email to this person at this time.” Amazon EventBridge Scheduler holds that intent with zero compute cost until the moment arrives, then triggers the scheduled action. See the Amazon EventBridge Scheduler User Guide for the full API reference and current service quotas.
For email campaigns, Amazon EventBridge Scheduler becomes the send-time dispatcher, the component that schedules every email in a campaign for its individually optimal moment, whether that’s timezone-adjusted, behavior-triggered, or sequence-driven.
Architecture diagram
The architecture follows an event-driven, per-recipient scheduling pattern for an email campaign. To start the campaign, you first define the target audience and the content they receive. Next, you need a way to create the per-recipient schedule. To do that for a campaign that can contain millions of recipients, you need a scalable mechanism to create the schedules. You can achieve this with an AWS Step Functions state machine, a serverless workflow service that coordinates multiple AWS services into structured, visual workflows called state machines. In this solution, we orchestrate the creation of the schedules by using a Distributed Map state within the state machine, which lets us fan out and accelerate schedule creation. It does this by splitting a large dataset into chunks and processing them across thousands of parallel child executions. It reads the recipient list from Amazon Simple Storage Service (Amazon S3), applies time zone logic per recipient, and creates an individual Amazon EventBridge Scheduler resource for each recipient in parallel. After the workflow creates all schedules, the execution completes.
The actual email delivery happens later, entirely decoupled from the campaign creation step. At the scheduled time, Amazon EventBridge Scheduler invokes Amazon Simple Email Service (Amazon SES) directly, passing the template name and personalization data as template variables. For campaigns requiring complex personalization logic (conditional content, real-time suppression checks, or data enrichment), you can optionally route through an AWS Lambda function before SES. If you need to adjust timing or content for specific recipients, you can update their individual schedules directly without reprocessing the entire campaign.
Figure 1: Per-recipient email scheduling architecture with Amazon EventBridge Scheduler
Walkthrough
The solution uses four core components that work together: a campaign manager to define send-time rules, Step Functions Distributed Map to fan out and accelerate schedule creation, Amazon EventBridge Scheduler to hold each per-recipient intent and deliver through Amazon SES directly, and automatic cleanup through schedule self-deletion.
How it works
- Create the campaign: A marketer defines the campaign: audience segment, email template, and send-time rules (for example, “9 AM in each recipient’s local time zone” or “24 hours before a Black Friday sale”).
- Campaign manager fans out: An AWS Step Functions workflow uses Distributed Map to iterate over the recipient list and create one Amazon EventBridge Scheduler schedule per recipient per campaign step directly through SDK integration. Each schedule encodes the exact send time for that individual.
- Amazon EventBridge Scheduler fires at the right moment: At each recipient’s scheduled time, Amazon EventBridge Scheduler invokes Amazon SES directly through a universal target, passing the template name and personalization data (recipient name and attributes) as template variables.
- SES personalizes and sends: Amazon SES renders the email template with the provided data and delivers the message.
- Schedule self-deletes:
ActionAfterCompletion='DELETE'prevents the accumulation of spent schedules.
Prerequisites
To follow along with this walkthrough, you need the following:
- AWS account and permissions: An active AWS account with permissions to create Amazon EventBridge Scheduler schedules, AWS Step Functions state machines, and Amazon SES identities, along with an AWS Identity and Access Management (IAM) role for Amazon EventBridge Scheduler to invoke Amazon SES.
- Development environment: Python 3.13 or later, AWS SDK for Python (Boto3) version 1.26 or later, and AWS Command Line Interface v2 (AWS CLI v2).
- Amazon SES configuration: Move your Amazon SES account out of sandbox mode to allow sending to arbitrary recipients.
Scaling the fan-out with Step Functions
For campaigns with millions of recipients, use AWS Step Functions Distributed Map to parallelize schedule creation. When you want to activate a campaign, you trigger a Step Functions workflow. This workflow fans out and creates schedules across the recipient list by using a Distributed Map with direct SDK integration. The direct SDK integration between Step Functions and Amazon EventBridge Scheduler lets each child execution call CreateSchedule directly. The following state machine definition reads recipients from an Amazon S3 CSV file and creates schedules in parallel:
Concurrency alignment with Amazon EventBridge Scheduler API limits
Step Functions Distributed Map supports up to 10,000 concurrent child workflows. Each child calls the CreateSchedule API directly, which has a default rate limit of 5,000 TPS. This limit is sufficient for most campaigns. If your campaign volumes require higher throughput, check your current quotas in the Service Quotas console and request an increase.
To avoid throttling, set MaxConcurrency below the CreateSchedule TPS quota. A value of 2,500 provides a comfortable buffer to account for bursts and retries without requiring a quota change. For larger campaigns, request an increase through AWS Service Quotas (adjustable to tens of thousands) and raise MaxConcurrency to match.
Canceling a campaign
A schedule group is an Amazon EventBridge Scheduler resource used to organize schedules. For this use case, we have a schedule group per campaign. If you need to pull a campaign (error in content, legal issue, or strategy change), you can cancel all scheduled sends for that campaign by deleting the entire schedule group. The following code shows how to cancel all pending sends for a campaign:
Operational considerations
Moving to production introduces a few scaling and reliability concerns to plan for.
Handling invocation spikes at delivery time
When a mass campaign schedules millions of messages for the same time, this creates cascading pressure across two limits:
- Amazon EventBridge Scheduler invocations throttle limit: The default is 1,000 TPS per AWS Region, and it is adjustable to tens of thousands of TPS through AWS Service Quotas. Amazon EventBridge Scheduler queues invocations internally and retries with exponential backoff when the downstream target throttles.
- Amazon SES sending quotas: Your SES account has a per-second sending rate. If the effective invocation rate exceeds this, messages fail with throttling errors. Align Amazon SES sending quotas with your campaign volume. Check your current SES quota in the Service Quotas console and request an increase before launching large campaigns. See Amazon SES best practices for deliverability at scale.
To handle an invocation spike, we recommend using the FlexibleTimeWindow feature of Amazon EventBridge Scheduler. Setting MaximumWindowInMinutes lets Amazon EventBridge Scheduler spread invocations across a time window rather than firing them all at the exact second. Size the window based on your campaign: divide the total schedules by your effective TPS to determine the minimum spread needed. For example, 500,000 schedules at 5,000 TPS need at least a 2-minute window.
Cost model
You pay for Amazon EventBridge Scheduler on a per-invocation basis.
Cleanup
To avoid ongoing charges, delete the resources created during this walkthrough:
- Delete any runtime-created schedule groups.
- Delete the Step Functions state machine.
Note: If you have active schedules still waiting to fire, deleting the schedule group will cancel all pending sends.
IAM role for Amazon EventBridge Scheduler and Step Functions
The Step Functions state machine needs an execution role with permissions to create schedules, send email, and pass the role to the Amazon EventBridge Scheduler service. Amazon EventBridge Scheduler needs permissions to call SES. The following policy shows the combined permissions for both scenarios:
This policy scopes the scheduler:CreateSchedule and scheduler:CreateScheduleGroup actions to resources prefixed with campaign-*, following least-privilege principles.
A condition restricts the iam:PassRole permission so that it can only pass the role to the Amazon EventBridge Scheduler service.
Conclusion
In this post, we walked through how to use Amazon EventBridge Scheduler to personalize email campaign delivery for each recipient. An email campaign system has two core problems: deciding what to send and deciding when to send it. Most teams over-engineer the “when” with polling infrastructure, batch jobs, and queue chains. Amazon EventBridge Scheduler collapses that into a single CreateSchedule API call per recipient.
To get started, explore Amazon EventBridge Scheduler on the AWS Management Console. Browse Serverless Land patterns for more than 20 Amazon EventBridge Scheduler patterns and other use cases beyond email campaigns.
Suggested tags: Amazon EventBridge, architecture, events, modernization, serverless.
How we could save petabytes of cache storage with Zstandard and Pingora
Post Syndicated from Aashi Patel original https://blog.cloudflare.com/cache-transcoding/
Memory costs are increasing dramatically. Both RAM and hard disk drive prices have exploded over the past year. At Cloudflare, we run several massively distributed storage products (including our famous CDN) that rely on making efficient use of the memory we have deployed so we can continue to serve all of our customers.
With this in mind, we prototyped a way to expand effective cache capacity. By encoding eligible assets with Zstandard inside Pingora, the architecture trades a minor CPU increase for significant storage and cross-data center bandwidth savings.
We have been prototyping a system called Cache Transcoding, which I built during my internship at Cloudflare as part of the 1.1.1.1 Intern Program. When an eligible response enters the cache, we encode it using Zstandard, or zstd, before writing it to disk. We keep that compressed form while the asset lives in the cache and moves between data centers via Tiered Cache, then decode it before serving the response to the client.
In our initial testing, this encoding shrunk eligible assets to ⅓ of their original on-disk size on average. The estimated extra CPU cost in our origin-facing proxy was small, but that is the trade. A small increase in CPU gives Cloudflare petabytes of effective cache capacity and reduces the data transferred between our data centers. The encoding cost is paid once when an asset enters the cache. The storage and bandwidth savings continue every single time that asset is reused.
What is Zstandard?
Zstandard, or zstd, is a lossless compression algorithm developed by Yann Collet at Facebook and open sourced in 2016. Lossless means that after compressed data is decoded, every byte is identical to the original. We can change how an asset is represented on disk without changing the asset itself.
Zstd is designed to balance compression ratio with speed. In our earlier browser compression testing, it compressed data 42% faster than Brotli while producing nearly the same file size, and produced files 11.3% smaller than gzip at a comparable speed. That balance matters because Cache Transcoding would touch a large amount of traffic, so both encoding and decoding need to stay fast.
The prototype uses zstd level 3, giving us most of the compression benefit without turning cache fills into a CPU bottleneck.
Cloudflare traditionally stores an asset using the content encoding supplied by its origin. If an origin sends an uncompressed response, we store those uncompressed bytes on disk and transfer them between data centers in the same form. Cache Transcoding adds compression inside the cache itself.
Not everything is worth compressing
Transcoding does not mean compressing everything. Images, video, and fonts are usually compressed already. In our traffic sample, this media slice represented 21.4% of requests but 63.3% of bytes. Compressing it again would burn CPU for nothing.
Compressible text is different. HTML, JSON, CSS, and JavaScript represented 67.3% of requests and 22.3% of bytes. Within that text slice, approximately 71% arrived uncompressed with Content-Encoding unset and it compresses well.
In our controlled test corpus, the eligible assets compressed by roughly 2.8 times.
Encoding is more expensive per byte, but assets are served far more often than they are filled.
By changing how assets are represented, existing hardware could store more customer content.
Fewer bytes on disk mean each server can retain more objects. This increases cache density and reduces the likelihood that useful content is evicted because an uncompressed representation consumed more space than necessary.
The smaller representation also helps as an asset moves through Tiered Cache because it reduces the data transferred between Cloudflare data centers, making backbone usage more efficient.
Paying the compression cost once
Compression is never free. Encoding and decoding both use CPU, so the important question is whether the byte savings are worth the processing cost.
At zstd level 3 (often the default balance of speed and compression size output), our model kept the extra CPU cost to a few percent under the traffic and reuse assumptions we tested.
We initially considered limiting transcoding to popular content, since hot assets are reused more, but it did not help. Decoding happens every time an asset is served, so limiting the feature to only the hottest content reduced the storage saving without cutting CPU by the same amount.
The simpler policy performed better. Transcoding all eligible compressible text at or above 4 kibibytes (KiB) captured nearly all of the measured storage benefit, while remaining within the CPU budget.
How Cache Transcoding works
On a cache miss, our Pingora-based proxy encodes the body using zstd before writing it to disk. The cache metadata records that the stored representation is compressed and preserves the original content length. Before the response leaves the proxy, the body is decoded back to its original identity representation.
On a cache hit, the stored zstd object is read from disk and decoded. With Tiered Cache, the compressed representation is transferred from the upper tier to the lower tier in the compressed form. Decoding only happens on the client-facing hop.
On a full cache miss, the upper tier fetches identity bytes from the origin. Those bytes are encoded once, stored as zstd, and transferred to the lower tier in their compressed form. The lower tier also stores the zstd representation, then decodes it for the request path.
If the lower tier misses but the upper tier already has the object, the origin is not involved. The compressed object moves directly between the cache tiers. It remains compressed on the wire and on disk, then is decoded once at the lower tier.
If the lower tier already has the object, no network transfer or encoding is needed. The lower tier reads the zstd bytes from disk, decodes them, and passes the original asset onward.
The storage encoding marker prevents an object from being encoded more than once. A cache layer receiving an object from another tier can see that it is already stored using zstd, and preserve it in that form.
Why we only transcode certain text
The fastest compression operation is the one we do not need to perform. Cache Transcoding therefore uses a series of eligibility checks to avoid content that is unlikely to benefit.
The prototype only transcodes a 200 OK response when Content-Encoding is unset, the Content-Type is compressible text, and the response has a known Content-Length of at least 4 KiB. Slice subrequests, responses using active upstream compression, range requests, precompressed responses, unknown length bodies, and binary content remain unchanged.
The 4 KiB threshold removed a large number of tiny requests while leaving out only about 1% of the otherwise eligible bytes. Lowering it would add per-object overhead without saving much more storage.
The threshold and zstd level are both parameters rather than permanent limits. We started with zstd level 3 and a 4 KiB minimum because they gave us a conservative way to measure the architecture. With the initial CPU budget understood, we can test whether higher compression levels improve the ratio enough to justify their additional cost.
Testing over one million requests through the cache
We exercised the prototype against a controlled test zone and correlated each request across request logs, Prometheus metrics, and Jaeger traces.
The correctness campaign covered cache misses, cache hits, single-hop fills, Tiered Cache fills, and more. We varied cache keys to make each request follow a specific path and used traces to confirm where encoding and decoding occurred.
One performance campaign sent more than a million requests across 10 cache servers. Half of the campaign ran with Tiered Cache disabled and the other half with it enabled. This allowed us to measure local cache behavior separately from transfers between cache tiers.
The two assets were approximately 195 KiB and 272 KiB, and both compressed by roughly 2.8 times. This was deliberately a compressible test corpus. It gave us a clear signal for validating the architecture, but it does not represent every text object on the Internet. A broader corpus is required before treating the measured compression ratio as a fleet-wide constant.
Compress once, benefit many times
What this experiment showed us is that there are significant efficiencies we can still deploy across our caching service that can benefit all of our customers. What we built for Cache Transcoding shows that the trade is favorable under the conditions we tested. The architecture preserved the content and remained within the CPU budget.
For next steps, we plan to evaluate higher zstd levels, test a broader range of content types and object sizes, tune different parameters from the eligibility criteria and more. Future work can also examine range requests, pre-compressed origin responses, and passing the compressed object directly to downstream components that already support it without decoding.
Throughout my internship, I’ve had the wonderful opportunity to work alongside Cloudflare's engineering teams on the real infrastructure that stores and serves content across our global network. If you want to start your career by helping build a better Internet, explore our internship opportunities and job openings.
THG Podcast: Counterfactuals – 1915 Battle of the Gulf of Riga
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=C5Lkf29B274
Rewiring Democracy Series on The Renovator
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/rewiring-democracy-series-on-the-renovator.html
Nathan E. Sanders and I are writing a series of essays on real-world examples of democratic technologies for The Renovator. I haven’t been posting the full text on the blog because they’re a bit long, but here are links.
Part 1 is about the Japanese digital democracy party, Team Mirai.
Part 2 is about the Swiss Public AI model, Apertus.
Part 3 is about the civic technologists of Open Knowledge Brazil.
And the new one, Part 4, is about civic AI in Scotland.
Президентски избори 2026 – подготовка
Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/pres26-prep/
На 25-ти октомври 2026 ще се проведат избори за президент и вицепрезидент. Ето най-важното към този момент.
Все още не е публикуван електронният формуляр за заявление за гласуване. Очакваме го до 11-ти септември, когато ще ви изпратя допълнителен мейл на абониралите се с нужната информация. Разбираме от хронограмата на ЦИК, че срокът на подаване е 29-ти септември. В последните 10 години времето за подаване на заявления варира от 17 дни на изборите през 2023-та до 28 дни през октомври 2024 и април 2021-ва. Както и на предишни избори, събирането на заявления ще се следи в реално време на карта на Glasuvam.org.
През 2026 г. бяха приети редица промени в Изборния кодекс. Преди парламентарните избори в началото на годината беше въведено ограничаване на броя секции в държави извън Европейския съюз. Как се стигна до това предложение и кои депутати гласуваха за него ще намерите обобщено в тези данни и на записа на дебатите в зала. Обобщил съм ги в тази статия. След изборите това ограничение отпадна, но остана правилото, че извън ЕС ще могат да се отварят секции само при 40 подадени заявления и по преценка на дипломатическите представителства. Това означава, че подаването на заявление е още по-важно от предходни години.
В следващите три дни – до 4-ти септември – трябва да бъдат обявени местата в чужбина, където в последните пет години е имало поне 100 гласували. Това ще включва 5-те вота от 25 октомври 2021-ва до сега. Изключва последните президентски изори, които се проведоха на 21-ви октомври. Отделно някои държави като Германия трябва изрично да дадат съгласие за досегашните места. Тук подаването на заявления отново ще е от значение, защото от една страна ще даде сведение на МВнР за местата, където има интерес, а от друга – ще бъде повод да се отварят повече секции на едно и също място предвид повишения интерес.
Важно е да се отбележи, че подаването на заявления не е задължително. Може да гласувате където и да е по света дори да не сте подали заявление или да не живеете постоянно в чужбина. Може да гласувате на което и да е място дори да сте подали заявление за друго. Заявленията обаче са критични за възможността Ви да упражните гласа си, както и за по-бързото провеждане на изборния ден.
Както стана видно в последните няколко вота, проблем с провеждането на изборите има, особено що се отнася до гладкото провеждане на изборния ден, надеждността на броенето, предотвратяване на злоупотреби и грешки. Затова, ако имате възможност, ви призовавам да се присъедините към секционните комисии или като доброволци. За целта се свържете с най-близкото до вас посолство като изявите това желание. Алтернативно, може да се присъедините като доброволец към инициативата ТиБроиш за следене честността на вота. Дори от дистанция може да участвате като следите излъчванията от секции в цяла България и да пренасяте данните от сниманите протоколи. В последните години много злоупотреби станали вече емблематични са били засечени именно по този начин. Може да се запишете тук и ще се свържат с вас за повече подробности.
Повече информация ще намерите на сайта на ЦИК, МВнР, както и в следващите статии в блога ми. Условията и редът за създаване на секции, провеждане на изборния ден и незабавните задачи пред посолствата и МВнР ще намерите в решението на ЦИК от 27-ми август.
Deliver real-time data to streaming tables for Apache Iceberg with Amazon Kinesis Data Streams
Post Syndicated from Nikit Pednekar original https://aws.amazon.com/blogs/big-data/deliver-real-time-data-to-streaming-tables-for-apache-iceberg-with-amazon-kinesis-data-streams/
Amazon Kinesis Data Streams now supports streaming tables, a fully managed capability that continuously delivers your streaming data as queryable Apache Iceberg tables on Amazon S3 Tables. Amazon S3 Tables is a capability of Amazon Simple Storage Service (Amazon S3). Streaming tables reduce data delivery costs to S3 Tables by up to 50% compared to self-managed alternatives and reduce downstream query costs by up to 30% through intelligent inline compaction that eliminates the small file problem. You need no custom applications, no self-managed compute, and no operational overhead.
Customers increasingly want to unify streaming data with Apache Iceberg for near-real-time analytics, fraud detection, personalization, and artificial intelligence and machine learning (AI/ML) feature pipelines. But integrating the two has meant operating complex custom connectors, managing format conversions, and contending with the performance impact of many small Parquet files that slow queries and increase costs. Streaming tables solve this: configure delivery in a few steps from the console or through APIs, and your data becomes queryable from Amazon Athena, Amazon Redshift, and Apache Spark within minutes. Tables are automatically registered in AWS Glue Data Catalog, making them immediately discoverable for analytics engines and AI agents.
For workloads that don’t require Iceberg table format, you can also deliver streaming data to Amazon S3 general purpose buckets. Delivery is in the source data format, ideal for archival, backup, and ML training data pipelines, with the same serverless, fully managed delivery and no infrastructure to operate.
Challenges with delivering streaming data to Apache Iceberg
Customers today face three challenges when integrating streaming data with Apache Iceberg.
Operational complexity: Connecting Kinesis Data Streams to Iceberg tables today requires deploying and maintaining custom connectors, Apache Flink jobs, or consumer applications. Teams must manage pipeline failures, handle format conversions, scale infrastructure, and monitor delivery reliability. These operational tasks consume significant engineering time and introduce ongoing risk of downtime.
Resiliency and the small file problem: Without proper coordination, simultaneous writes from multiple high-throughput shards can conflict, leading to failed commits, data freshness delays, and degraded performance. Streaming ingestion of high-volume data creates large numbers of small Parquet files in Iceberg tables, forcing a difficult trade-off between data freshness and query efficiency.
Cost: Customers typically spend up to $28/TB operating streaming extract, transform, and load (ETL) pipelines from Kinesis Data Streams using self-managed alternatives based on internal analysis. This creates a high price barrier to getting streaming data into queryable formats and makes cost unpredictable as volume grows.
How delivery to streaming tables solves these challenges
Streaming tables are a native capability built directly into Amazon Kinesis Data Streams. There is no separate service to deploy, no connector to version, and no consumer application to maintain. You enable delivery in a few steps from the console or through APIs.
Zero operational overhead: Streaming tables remove the need to build and operate custom consumer applications for data delivery. No pipeline infrastructure to provision, no scaling logic to write, no failure handling to implement. The capability automatically scales to process gigabytes per second of throughput.
Built-in resiliency: Streaming tables provide write coordination and exactly once delivery semantics across all shards in your stream, resolving concurrent writer conflicts and ensuring data integrity without manual intervention.
Intelligent compaction, no trade-offs: During ingestion, streaming tables perform inline compaction that produces query-optimized Parquet files, eliminating the small file problem while maintaining minute-level data freshness. This reduces downstream query costs by up to 30 percent compared to uncompacted delivery.
Consumption-based pricing: You pay only for data delivered: $14/TB for Iceberg delivery to S3 Tables in US East (N. Virginia) Region (us-east-1) (50% savings compared to self-managed alternatives) and $11/TB for general purpose S3 delivery (60% savings compared to self-managed alternatives). When your stream is idle, you pay nothing for delivery. Combined with Kinesis Data Streams On-Demand Advantage pricing, which eliminates per-shard charges and scales automatically, the entire path from ingestion to queryable Iceberg tables operates on a pure consumption model.
End-to-end managed streaming analytics architecture
With delivery to streaming tables, you now have a fully managed end-to-end real-time data architecture from data ingestion through storage to analytics. Your producers publish events to a Kinesis Data Stream, which continuously delivers data as optimized Iceberg read-only tables in S3 Tables. From there, you can query your streaming data using analytics engines like Amazon Athena, Amazon Redshift, Amazon EMR (Apache Spark), or Apache Flink. You can also let AI agents discover and reason over your data through Glue Data Catalog semantic search. This managed experience removes the intermediate infrastructure that customers previously assembled: separate connector clusters, compaction jobs, and custom consumers. It replaces them with a single, serverless pipeline from stream to insight.
The following diagram illustrates this end-to-end architecture.
Figure 1: End-to-end managed streaming analytics architecture from ingestion to query
Getting started
To get started, sign in to the Amazon Kinesis Data Streams console, navigate to your streams, and enable delivery to streaming tables in a few steps. Specify the stream you want to deliver, configure your schema settings using AWS Glue Schema Registry, and choose your destination S3 Tables location. After you enable it, delivery to streaming tables immediately begins materializing your streaming data as queryable Iceberg tables in S3 with no further intervention required. There’s no infrastructure to provision and no minimum commitment. You pay only for data delivered.
Additionally, you can use Amazon Kinesis Data Streams APIs to programmatically set up, update, or delete delivery to streaming tables configurations for your data streams. With these APIs, teams can build agentic workflows and infrastructure-as-code patterns to manage configurations across multiple data streams at scale.
Getting started with the Kinesis Data Streams Agent Skill
The Kinesis Data Streams Agent Skill provides AI-assisted guidance for setting up streaming tables integrations for your existing or new data streams. The skill helps you configure delivery to S3 Tables (Iceberg) or S3, including schema registry setup, AWS Identity and Access Management (IAM) role configuration, and validation.
Installing as an Agent Skill
Agent Skills are discovered automatically by compatible tools through the SKILL.md file. Refer to the Agent Toolkit for AWS Skill Installation Guide to install the managing-amazon-kinesis-data-streams Agent Skill. We also recommend you install the AWS MCP Server in your developer tool of choice, which exposes tools for searching AWS documentation, blogs, and Skills dynamically at runtime. These capabilities make agents more accurate and powerful for AWS related development and operational tasks, and make skill discovery and installation more flexible. Refer to Setting up the AWS MCP Server for guidance on installing the AWS MCP Server in your environment.
For example:
To verify the installation, interact with the skill in your preferred tool.
To start delivering data from your data streams to Apache Iceberg tables in real time, prompt “Create me a streaming table on my events data stream” to your agent of choice:
Figure 2: Prompting the agent to create a streaming table
The agent dynamically loads the managing-amazon-kinesis-data-streams skill and starts by gathering the available resources in your AWS account for the streaming tables integration. After it gathers that data, it confirms the resources to use or create, and creates the integration:
Figure 3: The agent confirming resources before creating the integration
After creating the integration, the agent summarizes the status and can then help with any other operational tasks with your data. For example, the agent can help you set up AWS Lake Formation permissions to query the data in S3 Tables with Athena, or configure your table maintenance behavior in S3 Tables:
Figure 4: The agent offering follow-up operational tasks
Conclusion
Streaming tables are available in all AWS Regions where Amazon Kinesis Data Streams is offered. Pricing is $14/TB for delivery to S3 Tables (Apache Iceberg) and $11/TB for delivery to general purpose S3 buckets. To learn more, visit the documentation and pricing pages.
About the authors
Measuring and improving search quality with Amazon OpenSearch Service
Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/measuring-and-improving-search-quality-with-amazon-opensearch-service/
Search is the front door of many applications, yet most teams struggle to answer a deceptively simple question: “Is my search actually returning relevant results?” Query logs tell you what users typed, not what they saw, what they selected, or why they left. When search feels broken, the culprit is rarely the engine. It’s the lack of deliberate signal collection, measurement, and a feedback loop to act on it.
You can close this gap on Amazon OpenSearch Service using User Behavior Insights (UBI), an open schema standard for capturing search behavior, and Search Relevance Workbench (SRW), a toolkit for measuring and evaluating search quality. Your application generates the UBI-formatted records. Together, UBI and SRW give you a repeatable framework: collect signals, turn them into relevance judgments, and validate every change before it ships.
In this post, we show you how to capture UBI data on an Amazon OpenSearch Service domain and use those signals to evaluate search quality. This is the first post in a two-part series. We build the foundation here, and Part 2 covers automating the workflow end to end.
The challenge: You can’t improve what you can’t measure
Consider a shopper searching for “handbag” on an ecommerce site. The catalog has 16 products (tote bags, duffel bags, laptop bags), but every title only says “bag.” The search returns zero results. Most shoppers leave. A patient one retries with “bag” and finds what they were looking for.
Your server log recorded that first query as a clean sub-second response: no error, no alert, no signal. What it missed entirely was a customer with purchase intent. That customer hit a vocabulary gap between how they search and how you write your catalog. Zoom out and apply this lens to misspelled queries, poor handling of long-tail searches, and abandoned sessions. The blind spot is larger than you think.
There’s a second problem: click signals are position biased. Users select the first result far more than the fifth, regardless of relevance, so raw click counts reflect where results appeared, not whether they deserved to be there. Any judgment derived from clicks must correct for this bias. We return to it when generating judgments.
Capturing behavioral data with UBI
UBI defines two indices. The ubi_queries index holds one record per executed query: the text the user typed, the full query that ran (filters and facets included), and the IDs of the documents returned. The ubi_events index holds every subsequent user action: impressions, hovers, clicks, add-to-carts, each stamped with the result position and the product’s business identifier (object_id). A shared query_id links every event back to the query that triggered it. Two additional identifiers complete the picture: client_id tracks the browser across visits, and session_id scopes events to a single visit.
A query record captures what the user asked and which document IDs the engine returned, including zero-result cases like the handbag search, which appears as a record with an empty result list. Here’s the shopper’s follow-up search for “bag”:
The UBI queries schema reference documents the complete query schema, including the mandatory attributes.
The event record captures what the user did next. For each result rendered, emit an impression event. When the user selects a result, emit a click event. Here is the impression event for the first result of the bag search:
event_attributes also accepts custom fields of your own alongside the standard position and object structures. The action_name attribute is critical: The judgment model you use later consumes only impression and click events. Treat a paginated results page as the same logical query: reuse the query_id and record absolute positions. The UBI events schema reference documents the complete event schema.
Collecting UBI data on Amazon OpenSearch Service
Behavioral data (what results ranked, what users saw, what they selected) exists only in the application layer. Your application owns the records, and Amazon OpenSearch Ingestion (OSI), a fully managed, serverless data collector powered by Data Prepper, provides the managed delivery path. Your application sends the records as SigV4-signed HTTP POST requests to the OSI pipeline endpoints. Route browser events through your backend for signing. One thing to understand before you write any code: Your application generates and owns the query_id attribute. The application creates the ID when it runs a search and stamps it on every subsequent event the user produces, until the user issues a new search or the session ends.
Prerequisites
To follow along, you need an Amazon OpenSearch Service domain running OpenSearch 3.5 or later with the OpenSearch UI application, permissions to create OpenSearch Ingestion pipelines with an AWS Identity and Access Management (IAM) pipeline role, and a search application you can instrument to emit behavioral records.
Create the UBI indices
Before you start collecting user metrics, you need the two indices in place with the right mappings. Field types matter here: query_id as keyword supports exact joins between queries and events, timestamp as date supports time-range queries, and event_attributes as dynamic means you can extend events with custom fields without schema changes.
Create ubi_queries first in Dev Tools. It holds the query-side records. We abbreviated the mappings here. Refer to the published queries-mapping.json file for the complete version:
Then create ubi_events. It holds every user action that follows (refer to the full events-mapping.json file):
With both indices created, the next step is routing data into them. You can deliver UBI data to your domain in several ways. This post uses OSI pipelines, shown end to end in the diagram that follows the setup.
Set up the OSI pipelines
Create two OSI pipelines: one for queries and another for events. Each pipeline exposes an HTTP source endpoint that your application writes to (shown on each pipeline’s console page) and sinks data to the corresponding index. The following configuration defines the events pipeline:
Note: the queries pipeline follows the same pattern, with /ubi/queries as the path and ubi_queries as the sink index and S3 prefix. Create the pipeline role yourself or let OpenSearch Ingestion create it. If your domain uses fine-grained access control, also map the pipeline role to a backend role so the domain accepts the pipeline’s writes. Refer to the tutorial Collecting UBI-formatted data in Amazon OpenSearch Service for detailed steps.
With the pipelines running, your application can start sending data. The following diagram illustrates the end-to-end flow:
Figure 1: The UBI collection pattern on Amazon OpenSearch Service
The workflow consists of the following steps:
- Users interact with your search application.
- The application sends signed query records to the OSI HTTP endpoint.
- OSI writes queries to the
ubi_queriesindex. - Users interact with the results, viewing and selecting documents.
- The application sends signed event records, carrying the same
query_id, to the OSI HTTP endpoint. - OSI writes events to the
ubi_eventsindex. - Optionally, both pipelines archive records to Amazon Simple Storage Service (Amazon S3).
- Search Relevance Workbench (OpenSearch UI) works with the collected data in the
ubi_queriesandubi_eventsindices.
Note: if you’re already collecting site analytics through an existing third-party tool, you don’t need to replace it. Map your search-related events (queries, clicks, and conversions) into the UBI schema and store them in OpenSearch. That’s enough to unlock the out-of-the-box evaluation framework, implicit judgment generation, and the full SRW metrics pipeline, without defining a single custom metric from scratch.
Visualize the data collected
After the UBI behavior metrics start to trickle in, you can review the data in the Discover tab on the OpenSearch UI dashboard. Filtering ubi_queries for empty result lists ranks your vocabulary gaps. You can also visualize the data collected through the sample User Behavior Insights (UBI) dashboards in OpenSearch.
Figure 2: UBI records in Discover, showing the zero-result handbag query and the follow-up bag query with its impressions and pagination events
With data flowing into your indices, keep these things in mind as you scale to production:
- Keep telemetry off the search critical path – Queue records and forward them asynchronously. Losing a fraction of behavioral data is statistically harmless. Blocking users isn’t.
- Manage volume deliberately – Batch impression events, and if you sample, sample whole queries rather than individual events to preserve the click-through ratios that drive judgments.
- Isolate analytical load for larger deployments – Route pipelines to a separate analysis domain with the same engine version, mappings, and analyzers as production. This keeps behavioral writes from touching live search latency.
- Plan for retention and integrity – Register the UBI mappings as an index template and apply an Index State Management (ISM) retention policy as your indices grow. You should validate and rate-limit the event write path, and cover query text and client identifiers with your data retention policy.
Evaluating search quality with Search Relevance Workbench
With ubi_queries and ubi_events collecting data, you now have the signals needed to evaluate search quality. Search Relevance Workbench, generally available in the OpenSearch UI from Amazon OpenSearch Service 3.5, turns those signals into structured experiments: comparing query configurations, scoring results against relevance judgments, and surfacing metrics that guide iterative tuning.
Figure 3: Search Relevance Workbench in the OpenSearch UI
SRW experiments rely on three components. You set them up once, then reuse them across every experiment you run: a query set (the fixed queries you evaluate against), search configurations (the query structures you want to compare), and a judgment list (the relevance ground truth). The following sections walk through each one.
Step 1: Create a query set
A query set is the fixed collection of queries you evaluate against. Keeping it fixed makes results comparable across experiments. Effective query sets reflect real traffic, not intuition. You can seed one from your top queries, a random sample, or a hand-picked mix that includes long-tail and low-performing queries. Alternatively, SRW can sample directly from ubi_queries using Probability-Proportional-to-Size (PPS) sampling, which selects queries in proportion to how often users issue them. This approach represents frequent queries like “bag”, so your metrics reflect search quality as users experience it.
Figure 4: Creating a query set sampled from real traffic in ubi_queries
Step 2: Define search configurations
A search configuration defines how a search executes: the index, the query structure, and a %SearchText% placeholder that SRW replaces with each query in your set. Creating two configurations and running them against the same query set and judgment list is how you validate a change before any user sees it.
As an example, here we define two configurations: a baseline multi_match query (retail_query) and a variant that boosts title matches (retail_boosted_query), so we can measure whether the boost actually helps ranking.
| retail_query | retail_boosted_query |
|
Configurations go beyond query variants: a candidate can be an entirely different retrieval strategy, like hybrid search combining keyword and neural retrieval. You can use judgments to rate query-document pairs independently of your retrieval approach. You can test a semantic or hybrid approach offline against your existing traffic before shipping it.
Step 3: Create the judgment list
A judgment is a relevance rating for a query-document pair: the ground truth that quality metrics measure against. You can create judgments that are explicit (from stakeholders or a large language model acting as judge), imported, or implicit (derived from behavior). Here we use implicit judgments derived from UBI selection behavior, scored using the Clicks Over Expected Clicks (COEC) model. The COEC model helps correct position bias by comparing each document’s actual click rate against the expected rate for its rank position. Documents that outperform their position score as relevant. Those that users select because they ranked first score near average.
Figure 5: Creating an implicit judgment list with the Implicit (Click based) type and the COEC click model
Three things to get right before you run experiments:
object_idin your events must match the document_idfrom your product catalog. The search configurations you define return this_id, which lets SRW join judgments to results.- Implicit judgments are statistical. They need volume and query coverage. As a working rule of thumb, aim for hundreds to thousands of real sessions per query to separate signal from noise.
- Max Rank controls how deep in the result list events count. If users paginate, set it beyond a single page. We use 20 here.
Step 4: Run experiments
This post uses three SRW capabilities: Query Analysis, Query Set Comparison, and Search Evaluation. Query Analysis is a quick eyeball check: compare two configurations side by side for a specific query to see exactly what changed and why the metrics moved. The other two answer harder questions with numbers: how good a configuration is, and how two configurations compare against real relevance signals.
Query Set Comparison (also called pairwise comparison) takes two configurations and computes ranking similarity. Jaccard overlap measures how much the two result lists share, while Rank-Biased Overlap (RBO) weights agreement at the top of the list more heavily. Near-identical scores mean the change will barely register with users. Low overlap means a real ranking shift worth reviewing carefully before shipping. In this run, the two configurations score 0.93 Jaccard and 0.92 RBO, a modest but real shift. SRW cannot score zero-result queries like “handbag”: They show zero similarity in a comparison and Failed in an evaluation, a signal they need a different fix than ranking adjustments.
Figure 6: Query Set Comparison showing Jaccard and Rank-Biased Overlap between the two configurations
Search Evaluation (also called pointwise evaluation) scores one configuration against your query set and judgment list across four metrics, each computed over the top k results (k=10 by default):
| Metric | What it measures | What it tells you |
| Coverage@k | Proportion of returned documents that have judgments | How much to trust the other three metrics. Low Coverage means many results were never judged |
| Precision@k | Fraction of the top k results that are relevant | How many irrelevant results appear on the first page |
| MAP@k (Mean Average Precision) | Precision averaged across ranks, rewarding relevant documents placed early | Whether relevant results appear early, even when Precision ties |
| NDCG@k (Normalized Discounted Cumulative Gain) | Graded judgment values, discounted by position (rank 1 counts more than rank 9) | Whether the best results appear first. The primary comparison metric |
Each pointwise experiment evaluates one configuration. To compare candidates, run one experiment per configuration and compare the results. In this run, the baseline (retail_query) scores Coverage@10 of 1.0, Precision@10 of 1.0, MAP@10 of 0.95, and NDCG@10 of 0.93, with the zero-result “handbag” query showing as Failed in the per-query detail.
Figure 7: Search evaluation results for one configuration: Coverage, Precision, MAP, and NDCG at 10, with per-query detail
From measurement to improvement
The preceding experiments are the harness. The following are common levers to test with it. Express each as a new search configuration, evaluate it against the same query set and judgment list, and adopt it only if the metrics move:
- Synonyms – One option for addressing known vocabulary gaps is to build synonyms. A search-time synonym token filter treats “handbag” and “bag” as equivalent, and with Amazon OpenSearch Service, you can hot deploy custom synonym packages without reindexing.
- Field weights – Adjust the fields and boosts in a multi_match query, like the
title^2variant tested earlier. - Semantic retrieval – A hybrid query combines keyword and neural scores, addressing vocabulary mismatch as a class rather than term by term. Judgments evaluate it offline exactly like a lexical candidate.
- Reranking – A rerank processor in a search pipeline reorders the top results using a cross-encoder model.
Clean up
To avoid future charges, delete the resources you created for this walkthrough:
- Delete the two OpenSearch Ingestion pipelines. To reuse them later, stop them instead. A stopped pipeline keeps its configuration and incurs no OpenSearch Compute Unit (OCU) hour charges.
- If you configured the optional Amazon S3 archive, delete the archived objects (or the bucket).
- If you keep the domain, optionally delete the
ubi_queriesandubi_eventsindices and the query sets, judgment lists, and experiments you created. These live on the domain and incur no separate charges. - If you created the domain specifically for this post, delete it to remove everything, including the resources in the previous step. Deleting a domain is irreversible. Don’t delete a domain that serves other workloads.
Conclusion
UBI collects the evidence, COEC turns it into judgments, and SRW experiments deliver the verdict: Coverage, Precision, MAP, and NDCG in place of guesswork. Ship the winning configuration, keep collecting, and the next round of judgments shows whether the improvement holds with real behavior. Where there used to be an opinion, there is now a number.
Everything here follows a repeatable pattern, and repeatable patterns lend themselves to automation. Part 2 walks through the Search Relevance Agent, available through the AI Assistant chat (the Ask AI button) in the OpenSearch UI. The agent analyzes your UBI signals, generates tuning hypotheses, and validates them offline before recommending changes. The pipeline you built in this post is the foundation. Stay tuned for Part 2.
To go deeper on the evaluation features, refer to the Search Relevance Workbench documentation.
About the authors
Amazon EC2 R9g and R9gd instances powered by AWS Graviton5 processors are now generally available
Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-ec2-r9g-and-r9gd-instances-powered-by-aws-graviton5-processors-are-now-generally-available/
Today, Amazon EC2 R9g and R9gd instances are generally available, powered by AWS Graviton5 processors. R9g instances are memory-optimized and deliver up to 25% better compute performance compared to Graviton4-based R8g instances, powered by the most energy efficient processor AWS has ever built.
R9g instances are ideal for memory-intensive workloads including databases, in-memory caches (Valkey, Redis, MemCached), real-time big data analytics, Linux-based workloads including containerized and micro-service-based applications (e.g. Kubernetes, Docker, EKS, ECS), as well as applications written in popular programming languages such as C/C++, Rust, Go, Java, Python, .NET Core, Node.js, Ruby, and PHP.
R9gd instances include local NVMe-based SSD block-level storage, ideal for memory-intensive workloads requiring fast, low-latency local storage such as open-source databases, distributed real-time big data analytics, large in-memory databases, and large caching workloads.
If you’re running workloads on R8g instances today, R9g gives you more performance per vCPU with faster memory, higher network and Amazon EBS bandwidth, and a larger L3 cache, all while using less energy.
What makes R9g different
Graviton5 processors bring several hardware improvements over Graviton4:
- Up to 25% higher compute performance per vCPU
- DDR5 8800 MT/s memory (up from 5600 MT/s in Graviton4), the fastest memory available in the cloud
- 5x larger L3 cache for better data locality
- Up to 2x higher network and EBS bandwidth for the largest instance sizes (up to 100 Gbps network, up to 72 Gbps EBS on the 48xlarge)
- Up to 3x higher packet-processing performance
R9g and R9gd instances support Instance Bandwidth Configuration (IBC), which lets you adjust the allocation of bandwidth between Amazon EBS and Amazon VPC networking by 25%. This helps optimize performance for workloads with specific bandwidth requirements such as databases and caching.
All R9g and R9gd instances run on the AWS Nitro System, which offloads virtualization, storage, and networking to dedicated hardware. This gives your applications near-bare-metal performance while maintaining strong security isolation between instances.
R9g and R9gd instances feature the Nitro Isolation Engine (NIE), the same enhancement to the Nitro System introduced with C9g and M9g instances earlier this year, which enforces isolation of instances and harnesses formal verification to provide assurances of isolation with mathematical precision. Nitro Isolation Engine is a purpose-built component that is responsible for enforcing isolation between virtual machines, including mediation of all access to virtual machine memory, CPU register state, and I/O devices through a minimal set of APIs. Nitro Isolation Engine leverages formal verification, a technique to mathematically demonstrate that the hardware or software behaves as intended, and not just in specific test cases. This intensive verification technique establishes Nitro as the first formally verified cloud hypervisor, pioneering a new standard for mathematically proven cloud security. To learn more about the Nitro Isolation Engine, visit the blog post. For details on the formal verification results, including scope and assumptions, see the technical white paper.
EC2 R9g and R9gd instance specifications
R9g and R9gd instances are each available in 11 sizes, from medium to metal-48xl. The following tables show the full specifications for each size.
| Instance size | vCPUs | Memory (GiB) | Instance Storage | Network Bandwidth (Gbps) | EBS Bandwidth (Gbps) |
| r9g.medium | 1 | 8 | EBS-Only | Up to 15 | Up to 12 |
| r9g.large | 2 | 16 | EBS-Only | Up to 15 | Up to 12 |
| r9g.xlarge | 4 | 32 | EBS-Only | Up to 15 | Up to 12 |
| r9g.2xlarge | 8 | 64 | EBS-Only | Up to 17 | Up to 12 |
| r9g.4xlarge | 16 | 128 | EBS-Only | Up to 17 | Up to 12 |
| r9g.8xlarge | 32 | 256 | EBS-Only | 17 | 12 |
| r9g.12xlarge | 48 | 384 | EBS-Only | 25 | 18 |
| r9g.16xlarge | 64 | 512 | EBS-Only | 34 | 24 |
| r9g.24xlarge | 96 | 768 | EBS-Only | 50 | 36 |
| r9g.48xlarge | 192 | 1536 | EBS-Only | 100 | 72 |
| r9g.metal‑48xl | 192 | 1536 | EBS-Only | 100 | 72 |
R9gd instances offer the same compute and networking performance as R9g, with the addition of local NVMe-based SSD storage for workloads that need fast, low-latency scratch space or temporary caches.
| Instance size | vCPUs | Memory (GiB) | Instance Storage (NVMe SSD) | Network Bandwidth (Gbps) | EBS Bandwidth (Gbps) |
| r9gd.medium | 1 | 8 | 1 x 59 GB | Up to 15 | Up to 12 |
| r9gd.large | 2 | 16 | 1 x 118 GB | Up to 15 | Up to 12 |
| r9gd.xlarge | 4 | 32 | 1 x 237 GB | Up to 15 | Up to 12 |
| r9gd.2xlarge | 8 | 64 | 1 x 474 GB | Up to 17 | Up to 12 |
| r9gd.4xlarge | 16 | 128 | 1 x 950 GB | Up to 17 | Up to 12 |
| r9gd.8xlarge | 32 | 256 | 1 x 1900 GB | 17 | 12 |
| r9gd.12xlarge | 48 | 384 | 3 x 950 GB | 25 | 18 |
| r9gd.16xlarge | 64 | 512 | 1 x 3800 GB | 34 | 24 |
| r9gd.24xlarge | 96 | 768 | 3 x 1900 GB | 50 | 36 |
| r9gd.48xlarge | 192 | 1536 | 3 x 3800 GB | 100 | 72 |
| r9gd.metal‑48xl | 192 | 1536 | 3 x 3800 GB | 100 | 72 |
Getting started
You can launch R9g and R9gd instances from the Amazon EC2 console using any supported Arm-based AMI. R9g instances support Amazon Linux 2023, Amazon Linux 2, Ubuntu 22.04+, RHEL 8.4+, SUSE Linux Enterprise Server 15 SP3+, Debian 12+, and other major Linux distributions.
If you’re migrating from R8g, no code changes are required for most applications. Select the equivalent R9g instance size and your application runs with better performance. For containerized workloads, R9g works with Amazon EKS, Amazon ECS, and standard Kubernetes deployments. Multi-arch container images built for Arm64 run without changes.
Several resources help you get started: the AWS Graviton Getting Started Guide covers how to build, run, and optimize workloads on Graviton-based instances. The Graviton Savings Dashboard helps you track cost savings. AWS Transform automates code transformations for migrating Java applications from x86 to Graviton. To learn more, visit AWS Graviton Processors or Level up your compute with AWS Graviton.
Pricing and availability
Amazon EC2 R9g and R9gd instances are available in US East (N. Virginia, Ohio), US West (Oregon), and Europe (Frankfurt) Regions.
R9g and R9gd instances are available for purchase through Savings Plans, On-Demand, Spot Instances, Dedicated Instances, or Dedicated Hosts. For detailed pricing, visit the Amazon EC2 pricing page.
Ready to get started? Launch R9g instances from the Amazon EC2 console. For more details, visit the Amazon EC2 R9g instances page.
If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this feature, try using the AWS MCP Server and plugins with your preferred AI tool. Share your feedback on AWS re:Post for Amazon EC2 or reach out through your usual AWS Support contacts.
— Daniel Abib
Trump Wants to Spend His War Chest on Himself
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=LCtUjyajlSg
We invited a direct competitor into Security Hub Extended. Here’s why.
Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/we-invited-a-direct-competitor-into-security-hub-extended-heres-why/
When customers keep pointing you to a solution that overlaps with parts of your own offering, you have a choice to make. This post is about the choice we made with Upwind, and why we’d make it again.
AWS Security Hub Extended exists because customers told us what was working for them in enterprise security and asked us to simplify adoption and integration. Upwind was one of the solutions customers kept naming, so we brought them in. Upwind didn’t only agree to participate, they committed fully to integration. They brought their full solution portfolio into Extended with aggressive pay-as-you-go pricing from day one. They got their field organization fully aligned on joint deal flow and have driven more customer activity and closed deals through Security Hub Extended than any other partner in the program.
Giving customers choice, even when it overlaps
Multiple best-of-breed options in cloud security—including one that overlaps with our own capabilities—are straightforward when you start with what customers need. Some will choose Security Hub Essentials for cloud security posture management and vulnerability scanning. Some will choose Upwind for runtime-first protection. Some will run both and get stronger outcomes from the combination. The customer decides, not us. That principle applies to every partner in Security Hub Extended. We listen to what’s working, and we simplify adoption through the same AWS relationship customers already have.
“Our customers run on AWS, and Security Hub is where their security operations live,” said Amiram Shachar, Co-Founder and CEO of Upwind. “Being inside Security Hub means customers get Upwind’s cloud workload protection with the same billing, the same support path, and the same operational model they already know. We’re here because it’s a better outcome for the customers we share.”
Who is Upwind?
Upwind is a cloud security company trusted by Siemens, Peloton, Roku, Wix, Nextdoor, and Nubank. Fast Company named them one of the Most Innovative Companies of 2026.
What makes them different is runtime. Most cloud security solutions scan configurations periodically and report what could be a risk based on static posture. Upwind deploys an eBPF-based sensor directly in the Linux kernel that sees what workloads are doing in real time, including process behavior, network connections, API calls, and container interactions. All observed continuously. That means Upwind can tell you not only what could theoretically be exploited, but what is actively at risk right now. That distinction cuts alert noise dramatically and lets security teams focus on what genuinely matters.
Better together. Not only with AWS, but with each other
Now extend that to the rest of your security stack. If you’re already running other Security Hub Extended solutions, they work together without you building the integrations.
A customer running Chainguard for supply chain security, Upwind for runtime protection, and Splunk for security operations gets a connected experience. Chainguard helps ensure clean, malware-resistant dependencies at build time. Upwind validates workload behavior at runtime and enriches those findings with real-time context. Everything flows into Splunk through Security Hub for unified triage. One experience, one bill, no custom integration work. The security team sees the full lifecycle from build to production without stitching tools together.
That same pattern applies with 7AI, where AI-driven automation can triage and investigate Upwind’s runtime events alongside endpoint, identity, and network signals, all without manual pipeline work.
This is the multi-way partnership that Security Hub Extended was designed to enable. These solutions aren’t only easier to buy together, they’re building toward each other. The findings flow into Security Hub in OCSF (Open Cybersecurity Schema Framework), get correlated and prioritized together, and route to the downstream tools your team already uses. Your security stack gets stronger as a whole, not only solution by solution.
How it works commercially
This isn’t a paper partnership. We’re closing multi-million dollar deals together through Security Hub Extended. Upwind has engaged faster than any other partner in the program, bringing their own customer opportunities and joining AWS-originated deals to close them jointly. One enterprise customer recently replaced their incumbent CNAPP with Upwind through a Security Hub Extended Private Offer. The deciding factors were runtime visibility that their previous solution couldn’t deliver and a single predictable commercial model that replaced complex per-module pricing across multiple vendors. The commercial model has momentum, and it’s because Upwind invested not only in signing an agreement but in the engineering and go-to-market work that makes joint success real.
Upwind is available through Security Hub Extended with pay-as-you-go pricing, one AWS bill, and no required long-term commitment. For enterprises that prefer committed-pricing agreements, Security Hub Extended Private Offers are also available with deeper discounts and the ability to aggregate spend across partners. You choose the path that fits how you buy. If you’re already running Security Hub for posture management and vulnerability scanning, adding Upwind gives you runtime visibility alongside what you already see. No new tooling to stand up, no new workflow to learn. It shows up in your existing prioritized view of risk.
What Upwind is building next
Upwind continues to expand. AI workload protection that monitors model behavior and agent tool calls at runtime. Windows Server VM coverage across AWS, Azure, and GCP. Deeper integration with the Security Hub correlation engine so runtime context enriches attack-path intelligence automatically. The partnership deepens as both sides invest.
“We believe runtime context and AWS-native signals together produce stronger outcomes than either alone,” said Amiram Shachar, Co-Founder and CEO of Upwind. “As Security Hub deepens its correlation and Upwind extends its runtime fabric, customers who use both will have a view of risk that no single solution can replicate. That’s the future we’re building toward together.”
What this means for you
Security Hub Extended exists to give you access to the solutions your peers are already succeeding with through the AWS relationship you already have. Upwind is what that philosophy looks like when applied to a category where AWS has an existing offering. We listened to customers, saw what was working for them, and made it available with the same commercial model as everything else.
Enable Upwind through the AWS Security Hub console. Pay-as-you-go. No commitment required. If you want to understand what consolidation looks like with Security Hub Extended, talk to your AWS account team.
We’re just getting started, but the momentum is real.
If you have feedback about this post, submit comments in the Comments section below.