Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=6sAm9Uscp2U
Automatic License Plate Readers Are Coming to Schools
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/automatic-license-plate-readers-are-coming-to-schools.html
Fears around children is opening up a new market for automatic license place readers.
Immigration Enforcement: Last Week Tonight with John Oliver (HBO)
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=DfTBhrkae74
S12 E20: Immigration Enforcement & The Baileys: 8/10/25: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=2psRpQvFSno
Sank After Sailing Only 1400 Yards
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/7cE4YKKiogA
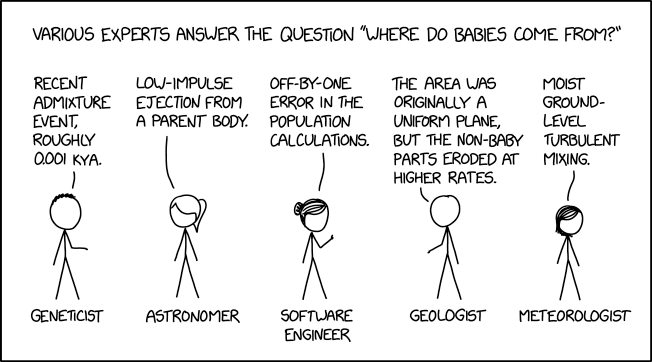
Where Babies Come From
Post Syndicated from xkcd.com original https://xkcd.com/3127/
Kioxia Shows LC9 for 8PB or More in 2U and 32-Layer Die Stacked NAND at FMS 2025
Post Syndicated from Eric Smith original https://www.servethehome.com/kioxia-shows-lc9-for-8pb-or-more-in-2u-and-32-layer-die-stacked-nand-at-fms-2025/
At FMS 2025 we saw the new Kioxia LC9 SSD that will allow for 8PB and larger 2U servers, 32-die stacked NAND cutaways, and an AI demo
The post Kioxia Shows LC9 for 8PB or More in 2U and 32-Layer Die Stacked NAND at FMS 2025 appeared first on ServeTheHome.
Kernel prepatch 6.17-rc1
Post Syndicated from corbet original https://lwn.net/Articles/1033168/
Linus has released 6.17-rc1 and closed the
merge window for this development cycle.
Anyway, the merge window did end up looking fairly healthy, despite
me having to go through a couple of bisections for trouble spots
(one during travels with a laptop – not optimal, but thankfully it
was at least one of the “reliable symptoms that bisect right to the
culprit” kind). The stats look pretty normal both in patch size and
in number of commits.
In the end, 11,404 non-merge changesets found their way into the mainline
during the merge window.
Boeing & DPAs #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/lrZlBPJYH-Y
Comic for 2025.08.10 – Literally Me
Post Syndicated from Explosm.net original https://explosm.net/comics/literally-me
New Cyanide and Happiness Comic
self-raising
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/self-raising/
Debian 13 (“trixie”) released
Post Syndicated from jzb original https://lwn.net/Articles/1033134/
The Debian Project has released its latest stable version, Debian 13
(“trixie”), which will be supported through 2030. This release
includes GNOME 48, KDE Plasma 6.3, Xfce 4.20,
Linux 6.12, GCC 14.2, Python 3.13, and
systemd 257.
This release contains over 14,100 new packages for a total count of
69,830 packages, while over 8,840 packages have been removed as
“obsolete”. 44,326 packages were updated in this release. The overall
disk usage for “trixie” is 403,854,660 kB (403 GB), and is made up of
1,463,291,186 lines of code. […]With this broad selection of packages and its traditional wide
architecture support, Debian once again stays true to its goal of
being “The Universal Operating System“. It is suitable for many
different use cases: from desktop systems to netbooks; from
development servers to cluster systems; and for database, web, and
storage servers. At the same time, additional quality assurance
efforts like automatic installation and upgrade tests for all packages
in Debian’s archive ensure that “trixie” fulfills the high
expectations that users have of a stable Debian release.
Trixie adds riscv64 as an officially supported architecture, and
drops i386 as a regular architecture. Users with i386 systems should
not upgrade to trixie; the project recommends reinstalling them as
amd64, or retiring the hardware. See the release
notes and issues
to be aware of before installing or upgrading to trixie.
Comic for 2025.08.09 – HEY YOU!
Post Syndicated from Explosm.net original https://explosm.net/comics/hey-you
New Cyanide and Happiness Comic
PCIe 8.0 Announced by the PCI-SIG Will Double Throughput Again
Post Syndicated from Cliff Robinson original https://www.servethehome.com/pcie-8-0-announced-by-the-pci-sig-will-double-throughput-again/
PCIe 8.0 has been announced by the PCI-SIG, and it is set to double bandwidth yet again, with a targeted 2028 specification release
The post PCIe 8.0 Announced by the PCI-SIG Will Double Throughput Again appeared first on ServeTheHome.
Sony PS-FL99 vinyl record player with an unusual digital feature.
Post Syndicated from Techmoan original https://www.youtube.com/watch?v=RPsa9O1PFhY
Желязков продължава разпродаването на държавни имоти с над 20 търга
Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/proekt-targove/
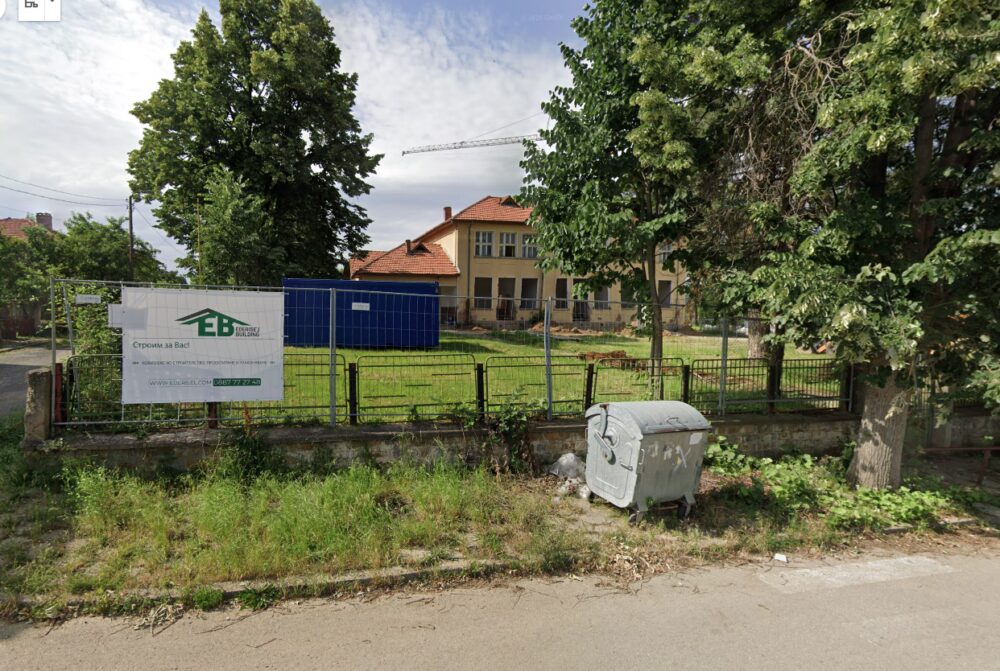
Както писах в четвъртък, в рамките на 48 часа след отговора на Желязков на критиките ми бяха проведени два търга, един от които от списъка с „отпаднала“ необходимост. Именно той беше продаден за 23100 лв. Представлява земя с рушаща се сграда в с. Голям Желязна в Ловеч. В парцела попада и трафопост, който не е обект на продажба. Купувачът е инициатива за създаване на кулинарно училище, която е купила сградата на местното училище в селото и го е възстановила за нов живот. Сега купуват този имот в близост. Не знам нищо за работата им, но от малкото прочетено определено искам да знам повече.
По всичко личи, че това е положителен пример за държавна земя, която влиза в ръцете на хора, които искат да правят нещо полезно и смислено с нея, показва отново че отговорът на Желязков е подвежда обществото. Показва също колко хаотично е правен списъка и се подхожда към тези продажби, защото сред държавните имоти с „отпаднала необходимост“ виждаме също въпросната сграда на селското училище купено от същата фирма още преди години.
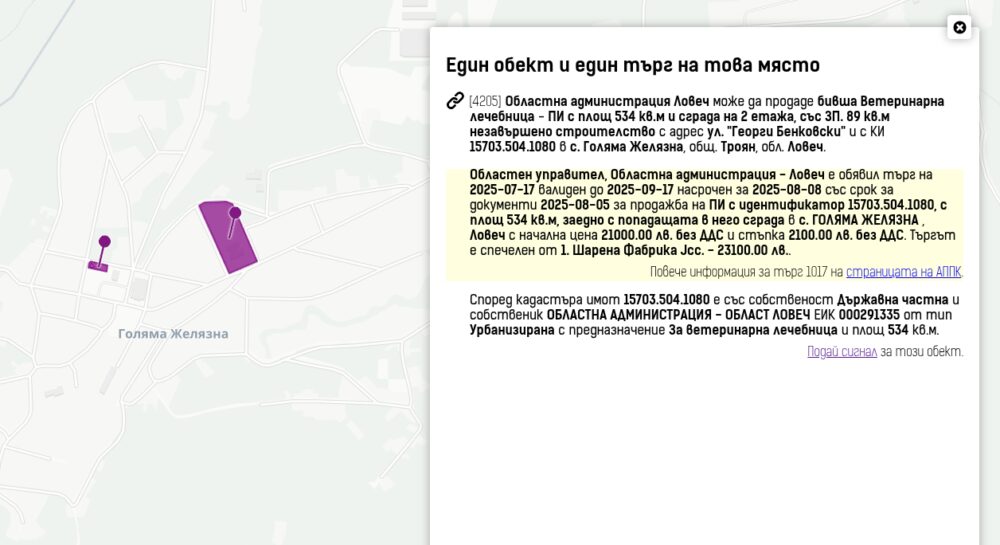
Бъдещите търгове са също на картата
Намерих обаче още нещо и снощи прекарах отново значително време да сложа на картата. На страницата на АППК има списък с текущи проекти за нови търгове. Тоест информация за имоти, които ще най-вероятно ще обявяват за продажба.
Към този момент виждаме 25 такива проекта. 15 от тях засягат имоти в списъка на Желязков и по-специално 34 парцели или сгради в него. Това означава още 14 търга отгоре на 6-те, за които говоря горе, които може да бъдат обявени и в някои случаи продадени преди края на ваканцията на Народното събрание. Нещо, с което Желязков е напълно наясно излизайки с тази формулировка на отговора си.
Тези проекти ще намерите в нов филтър на картата „Проекти за търгове“. Показват номер, който се състои от датата, когато съм ги видял последно и пореден номер в този документ. Тъй като е Excel таблица, не изглежда да имат уникални номера, затова съм направил такъв сам. Таблицата обаче изглежда се съставя доста добре, така че ще може да следим какво идва като нови търгове. Информацията съдържа само описание на обектите и данъчна оценка. Аз добавям освен кога съм видял за пръв път проекта, кога за последно е бил там или кога виждам, че е махнат от списъка. Тогава, ако има обявен търг, той ще се види на същото място.
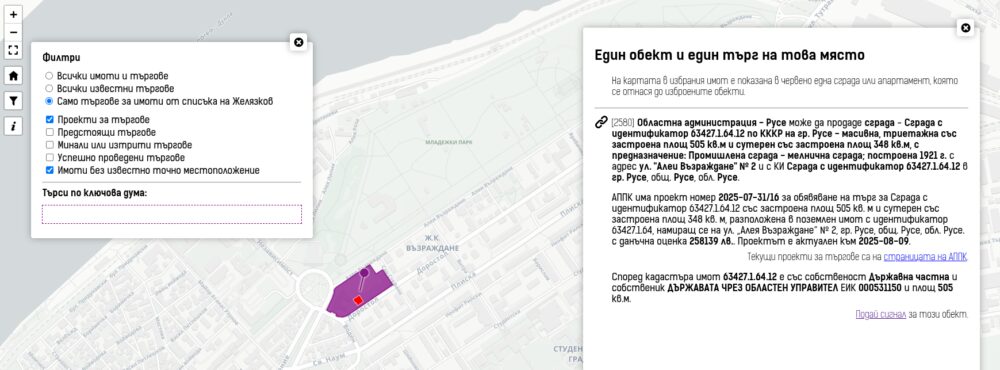
Ето например такъв проект за сграда до Младежкия парк в Русе – номер в списъка на Желязков 2580, собственост Областна администрация Русе и данъчна оценка 258 хиляди лева.
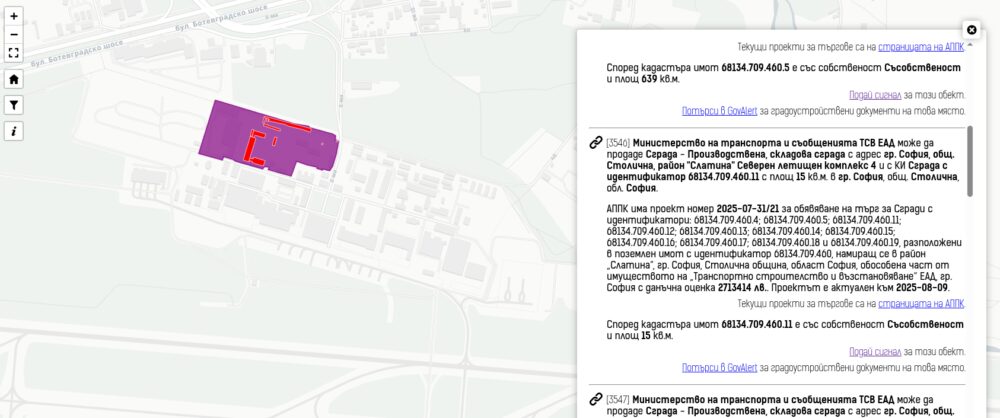
Ето пример и с 11 сгради зад летище София с обща данъчна оценка от 2.7 млн. лв.
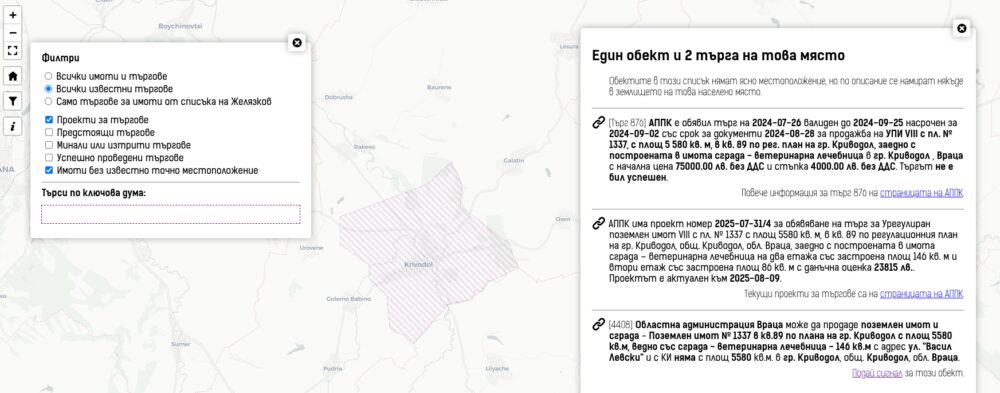
Тъй като виждам само последният списък с проекти, това не значи, че някои от тях не са започнали доста по-отдавна. Също, данъчната оценка видимо няма да е началната цена на търговете. Например, има един проект в Криводол, където нямам кадастриален идентификатор и мога да го покажа само към населеното място. Виждаме на същото място търг, който не е успешен през 2024-та с начална цена 75 хил. лв. Към сегашна дата виждаме проект за продажба на същото с данъчна оценка под 24 хил. лв. Т.е. опитват се отново и вероятно търгът ще е за повече.
Този пример показва трудността да се свържат проекти, търгове и имоти в списъка за разпродажба на кабинета, когато няма точна информация за местоположението. Търся начин да реша този проблем, за да не пропускаме тези случаи.
The post Желязков продължава разпродаването на държавни имоти с над 20 търга first appeared on Блогът на Юруков.
Friday Squid Blogging: New Vulnerability in Squid HTTP Proxy Server
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/friday-squid-blogging-new-vulnerability-in-squid-http-proxy-server.html
In a rare squid/security combined post, a new vulnerability was discovered in the Squid HTTP proxy server.
Friday Live Tech Chat Q&A
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=nk2suA0xRVc
The Amazon SageMaker lakehouse architecture now automates optimization configuration of Apache Iceberg tables on Amazon S3
Post Syndicated from Tomohiro Tanaka original https://aws.amazon.com/blogs/big-data/the-amazon-sagemaker-lakehouse-architecture-now-automates-optimization-configuration-of-apache-iceberg-tables-on-amazon-s3/
As organizations increasingly adopt Apache Iceberg tables for their data lake architectures on Amazon Web Services (AWS), maintaining these tables becomes crucial for long-term success. Without proper maintenance, Iceberg tables can face several challenges: degraded query performance, unnecessary retention of old data that should be removed, and a decline in storage cost efficiency. These issues can significantly impact the effectiveness and economics of your data lake. Regular table maintenance operations help ensure your Iceberg tables remain high performing, compliant with data retention policies, and cost-effective for production workloads. To help you manage your Iceberg tables at scale, AWS Glue automated those Iceberg table maintenance operations: compaction with sort and z-order and snapshots expiration and orphan data management. After the launch of the feature, many customers have enabled automated table optimization through AWS Glue Data Catalog to reduce operational burden.
The Amazon SageMaker lakehouse architecture now automates optimization of Iceberg tables stored in Amazon S3 with catalog-level configuration, optimizing storage in your Iceberg tables and improving query performance. Previously, optimizing Iceberg tables in AWS Glue Data Catalog required updating configurations for each table individually. Now, you can enable automatic optimization for new Iceberg tables with one-time Data Catalog configuration. Once enabled, for any new table or updated table, Data Catalog continuously optimizes tables by compacting small files, removing snapshots, and unreferenced files that are no longer needed.
This post demonstrates an end-to-end flow to enable catalog level table optimization setting.
Prerequisites
The following prerequisites are required to use the new catalog-level table optimizations:
- An active AWS account.
- A data lake administrator to configure the table optimizations at the catalog level. To create the data lake administrator, refer to Set up AWS Lake Formation.
- An AWS Identity and Access Management (IAM) role for the table optimizations to access Iceberg tables. For the instructions, refer to Catalog level table optimization prerequisites.
Enable table optimizations at the catalog level
The data lake administrator can enable the catalog-level table optimization on the AWS Lake Formation console. Complete the following steps:
- On the AWS Lake Formation console, choose Catalogs in the navigation pane.
- Select the catalog to be enabled with catalog-level table optimizations.
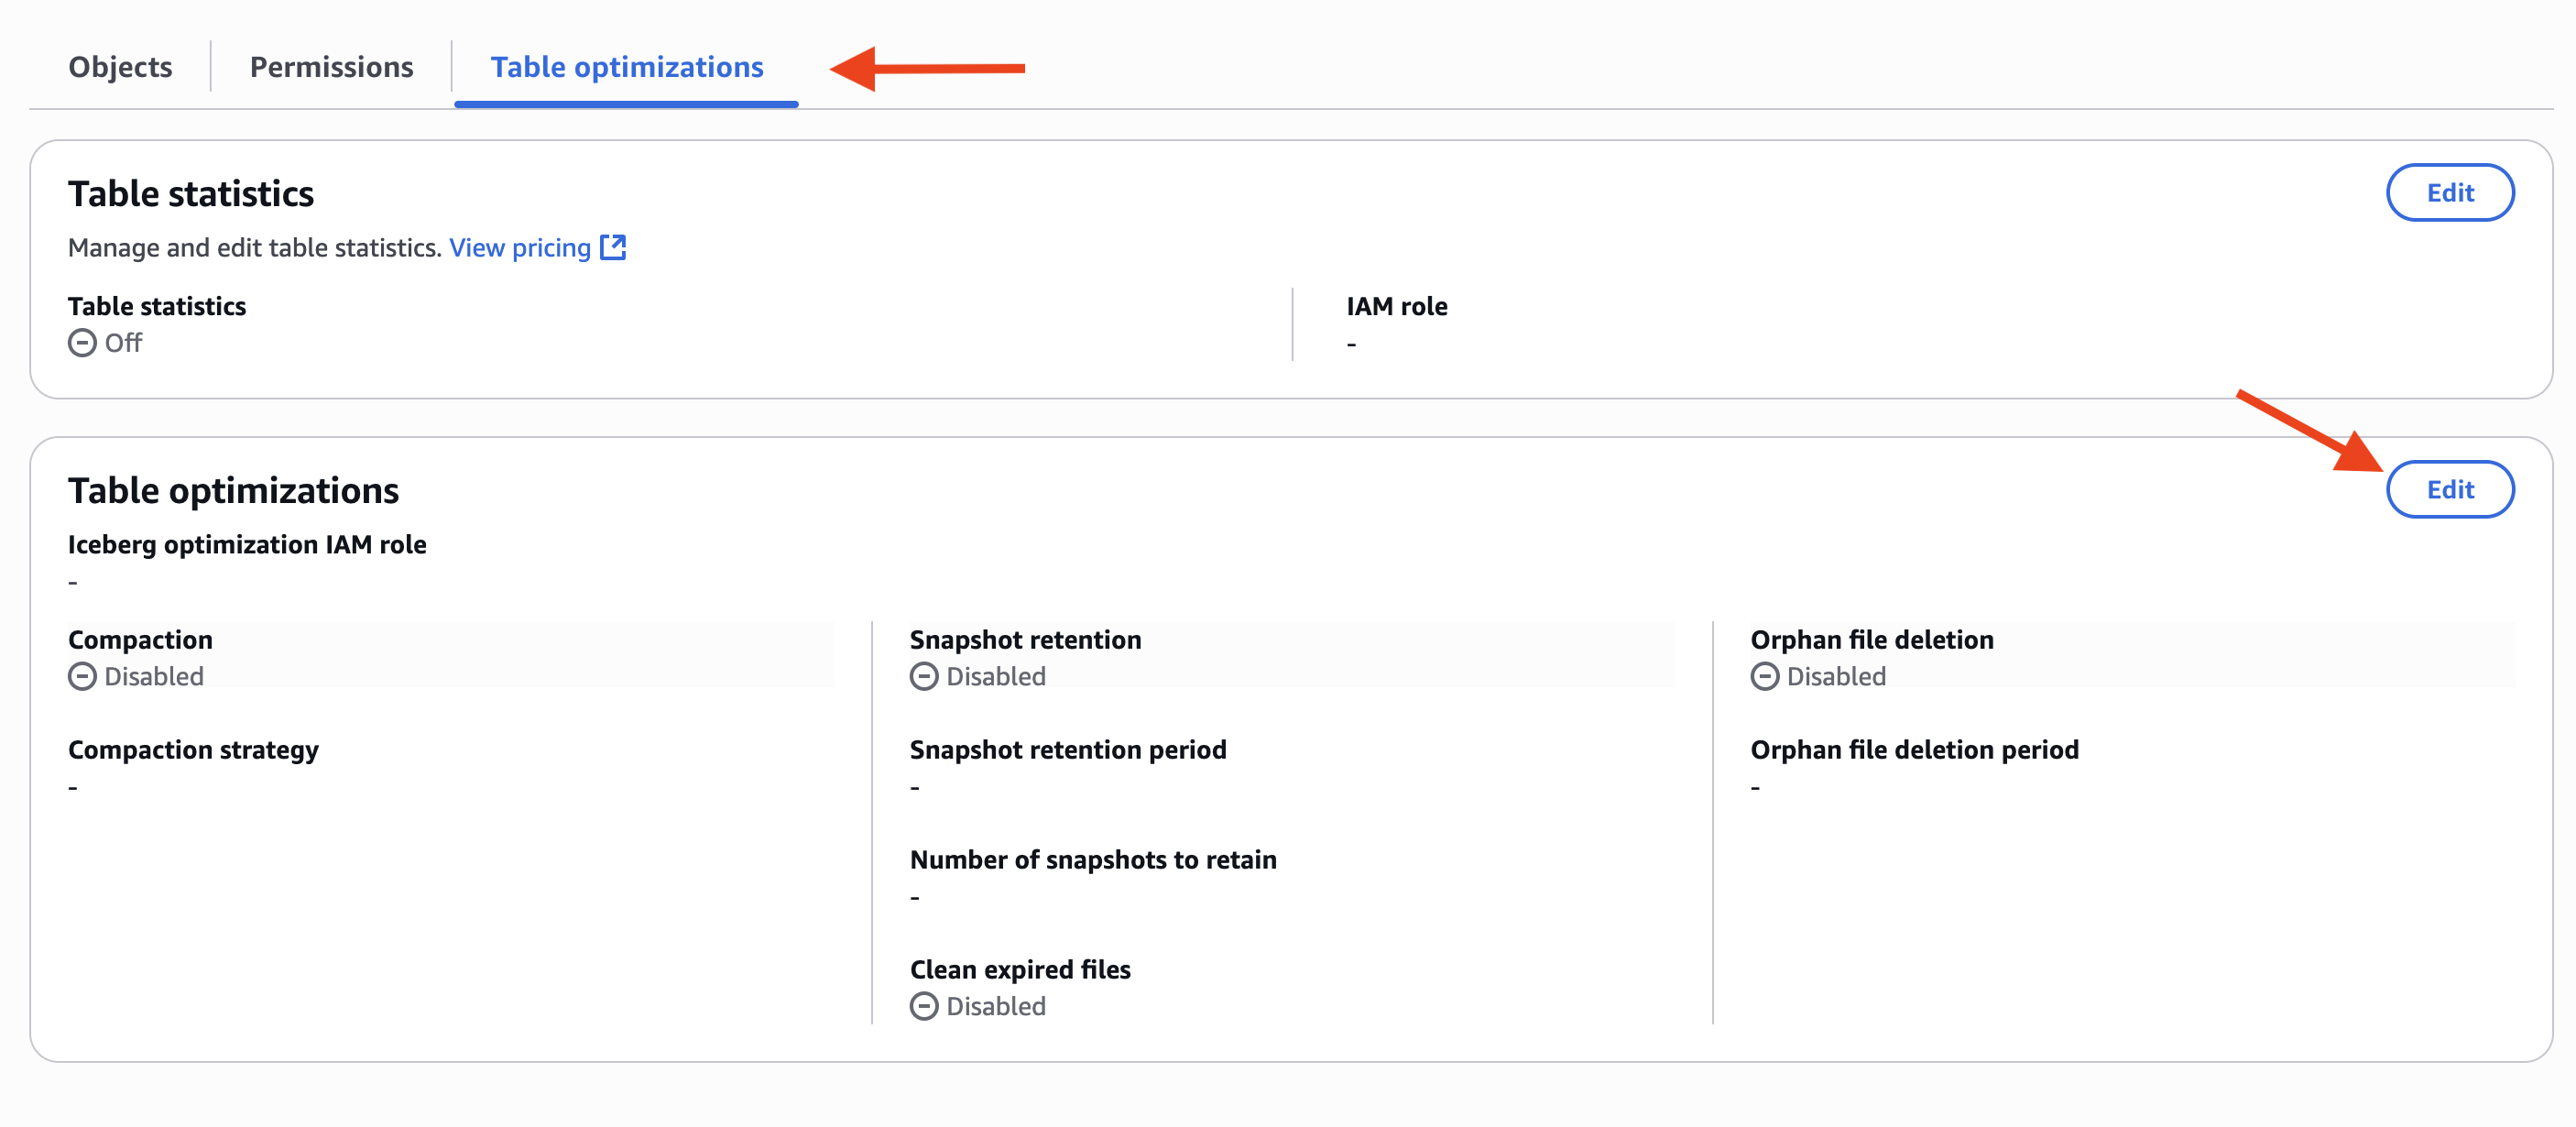
- Choose Table optimizations tab, and choose Edit in Table optimizations, as shown in the following screenshot.
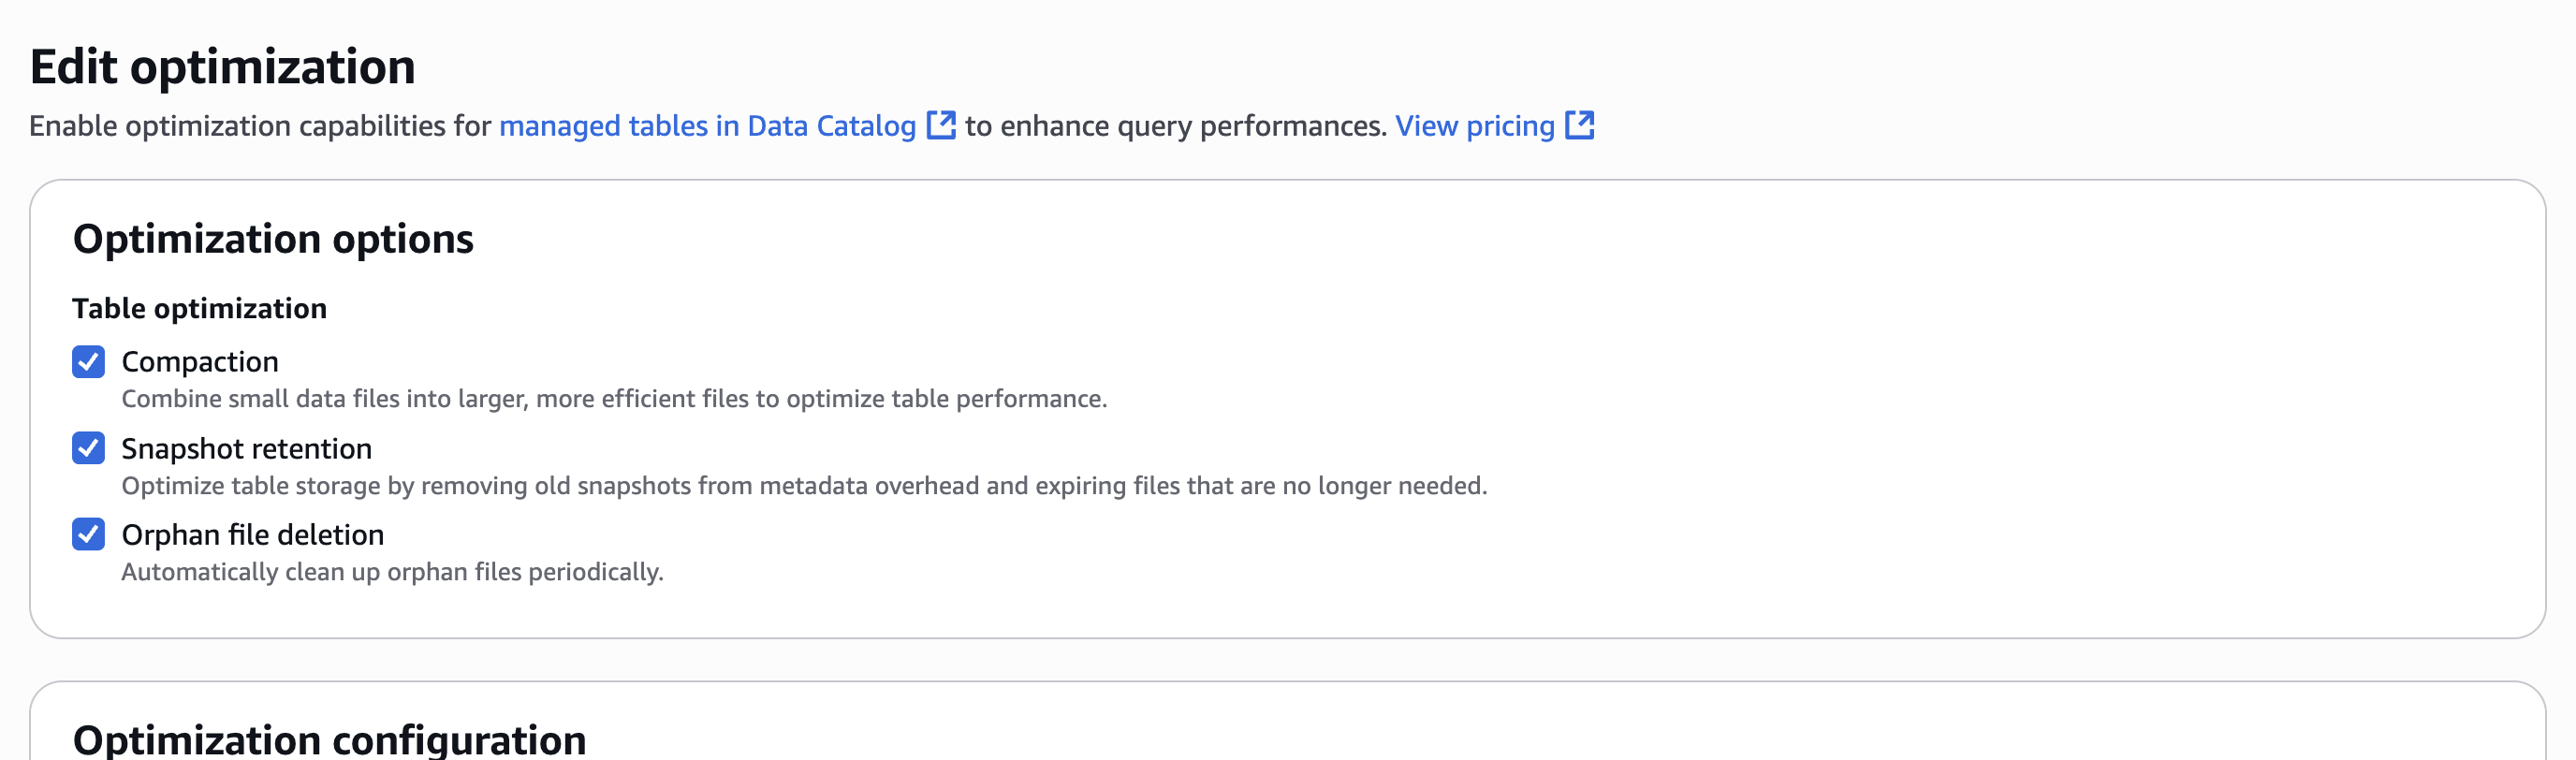
- In Optimization options, select Compaction, Snapshot retention, and Orphan file deletion, as shown in the following screenshot.
- Select an IAM role. Refer to Table optimization prerequisites for permissions.
- Choose Grant required permissions.
- Choose I acknowledge that expired data will be deleted as part of the optimizers.
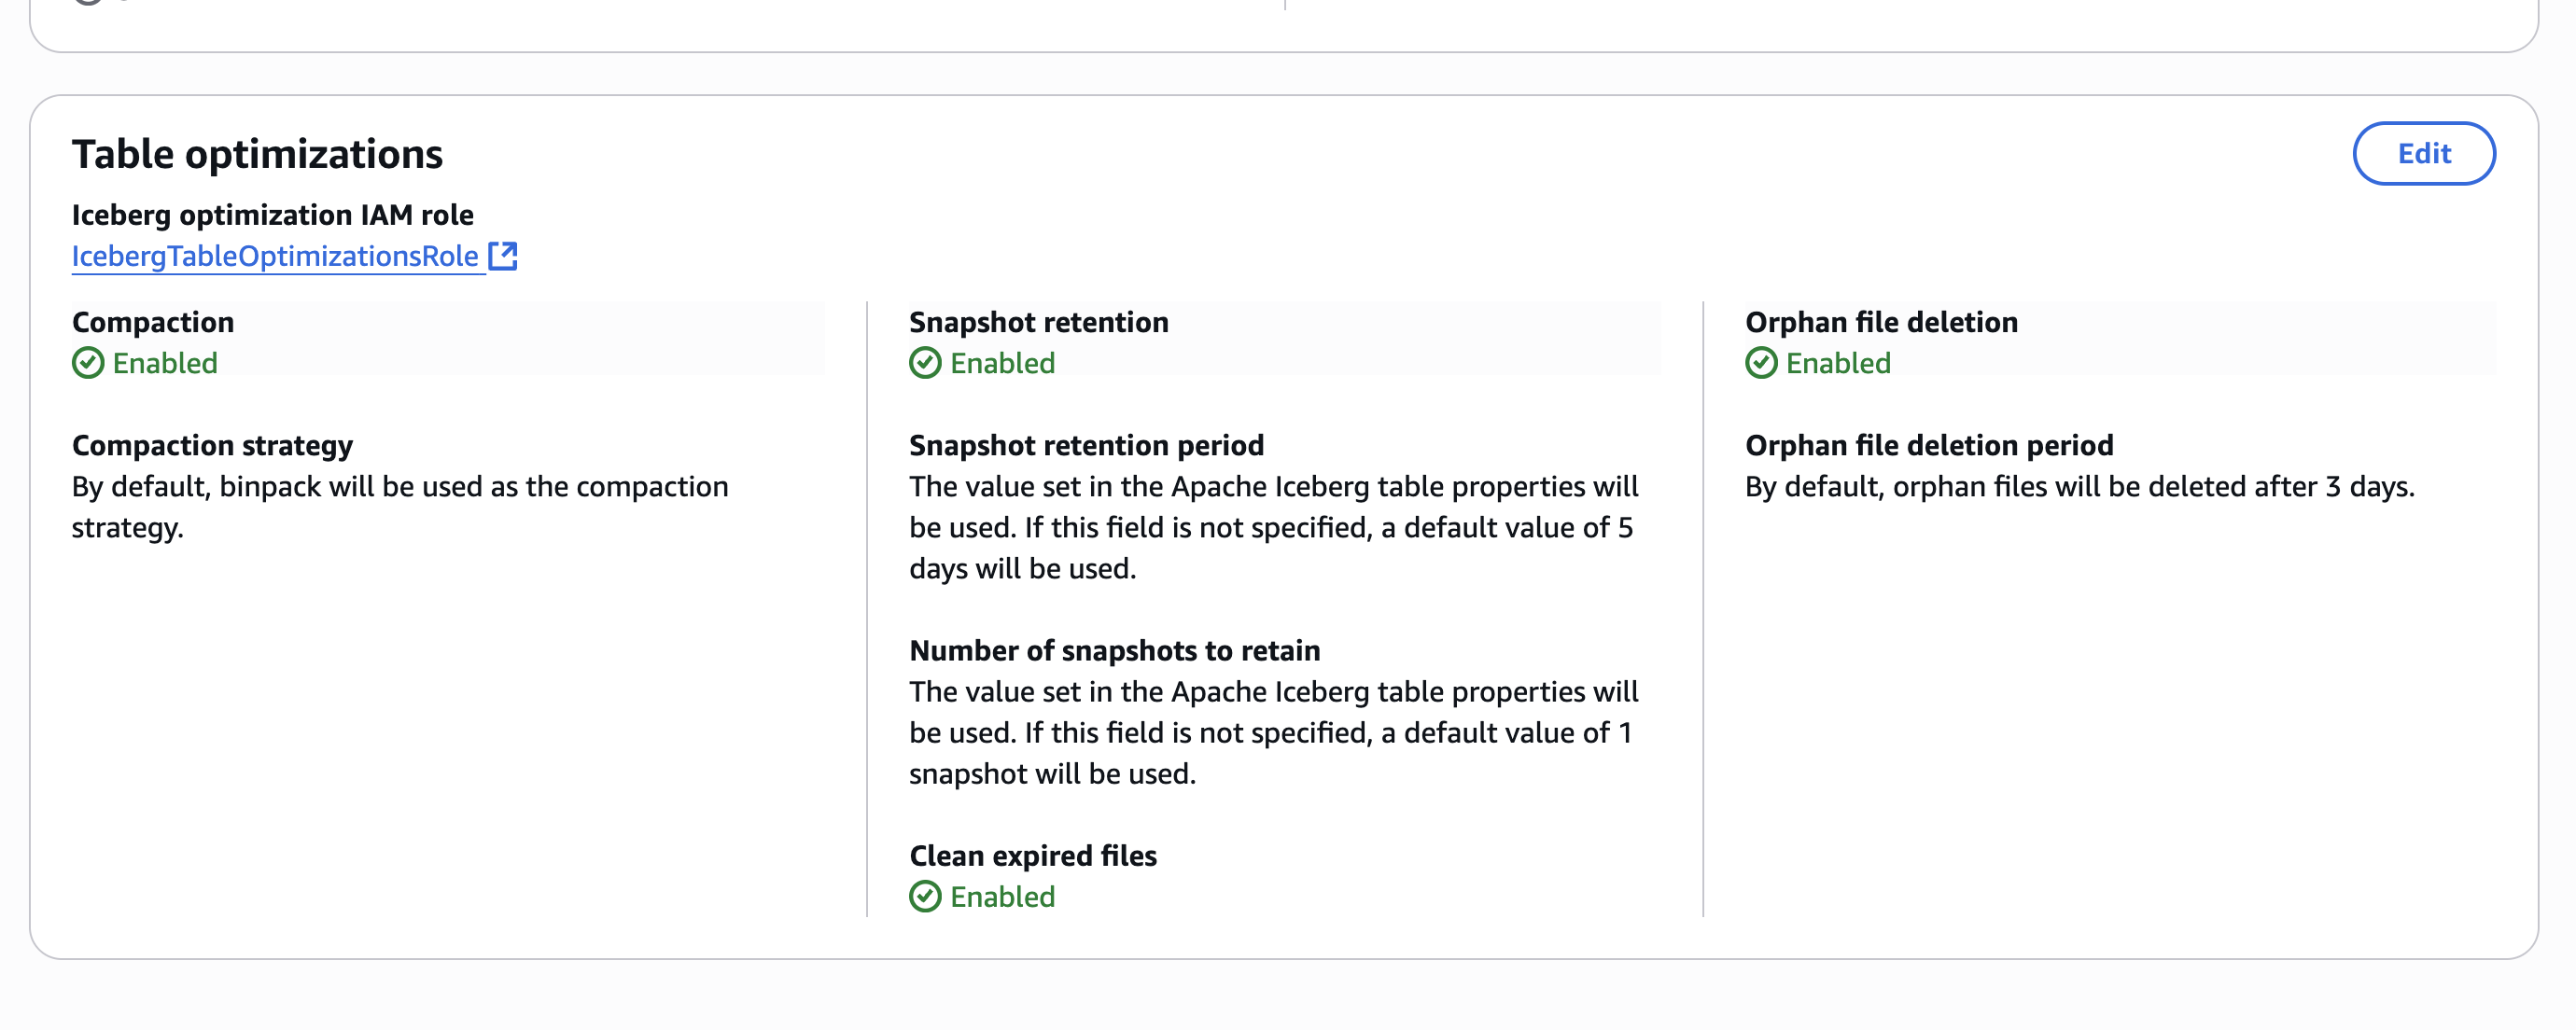
After you enable the table optimizations at the catalog level, the configuration is displayed on the AWS Lake Formation console, as shown in the following screenshot.
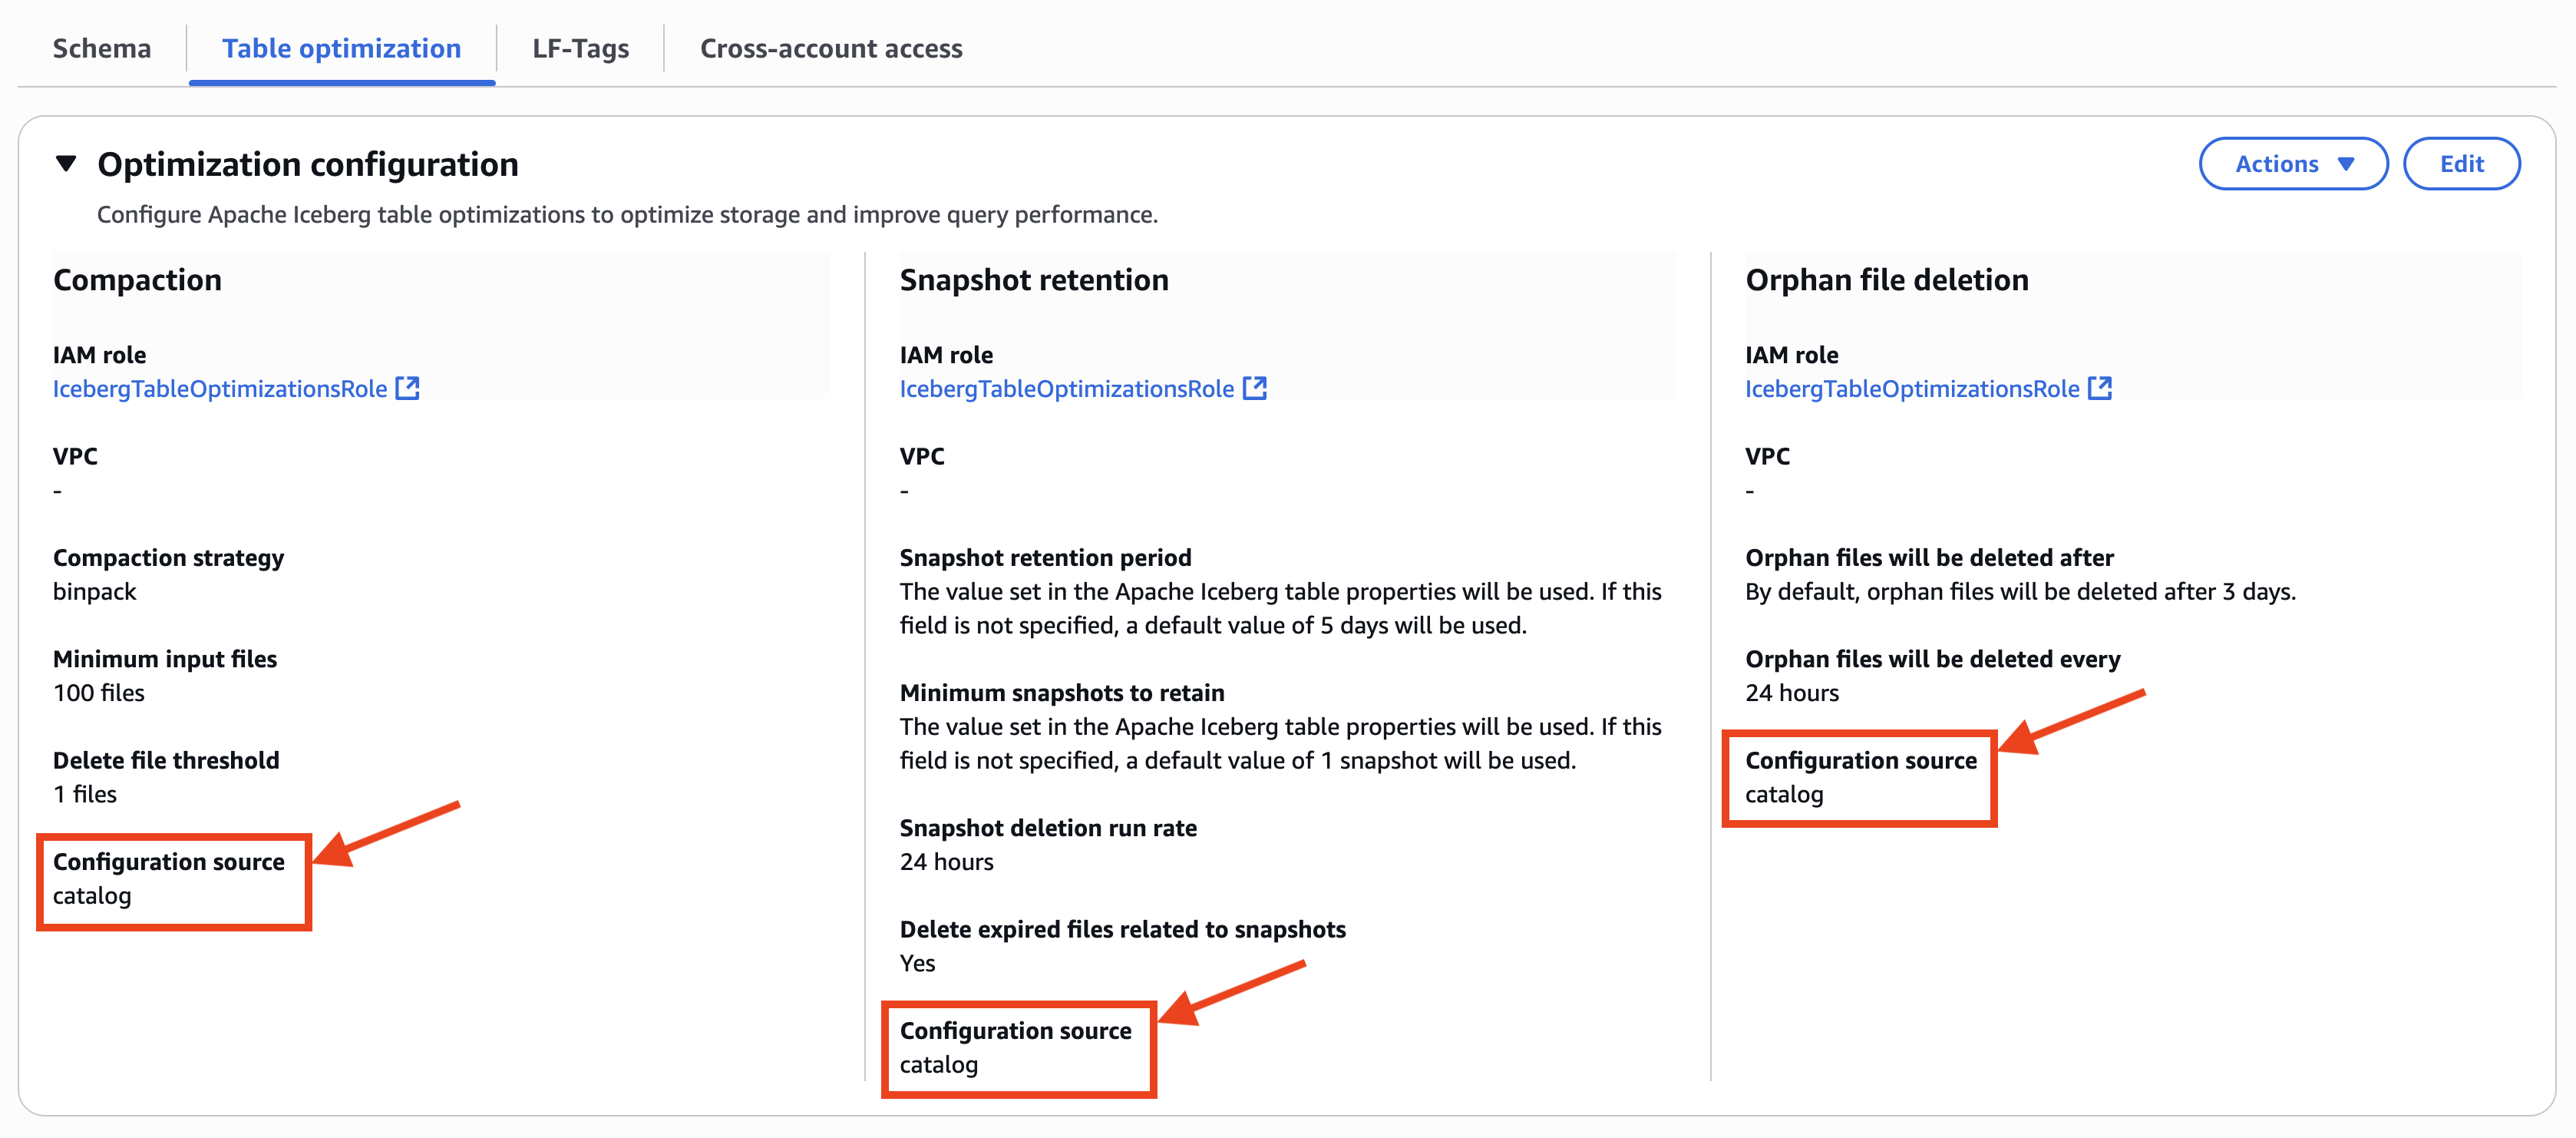
When you select an Iceberg table registered in the catalog, you can confirm that the table optimizations configuration is inherited from the table view because Configuration source shows catalog, as shown in the following screenshot.
The table optimizations history is displayed on the table view. The following result shows one of the compaction runs by the table optimizations.
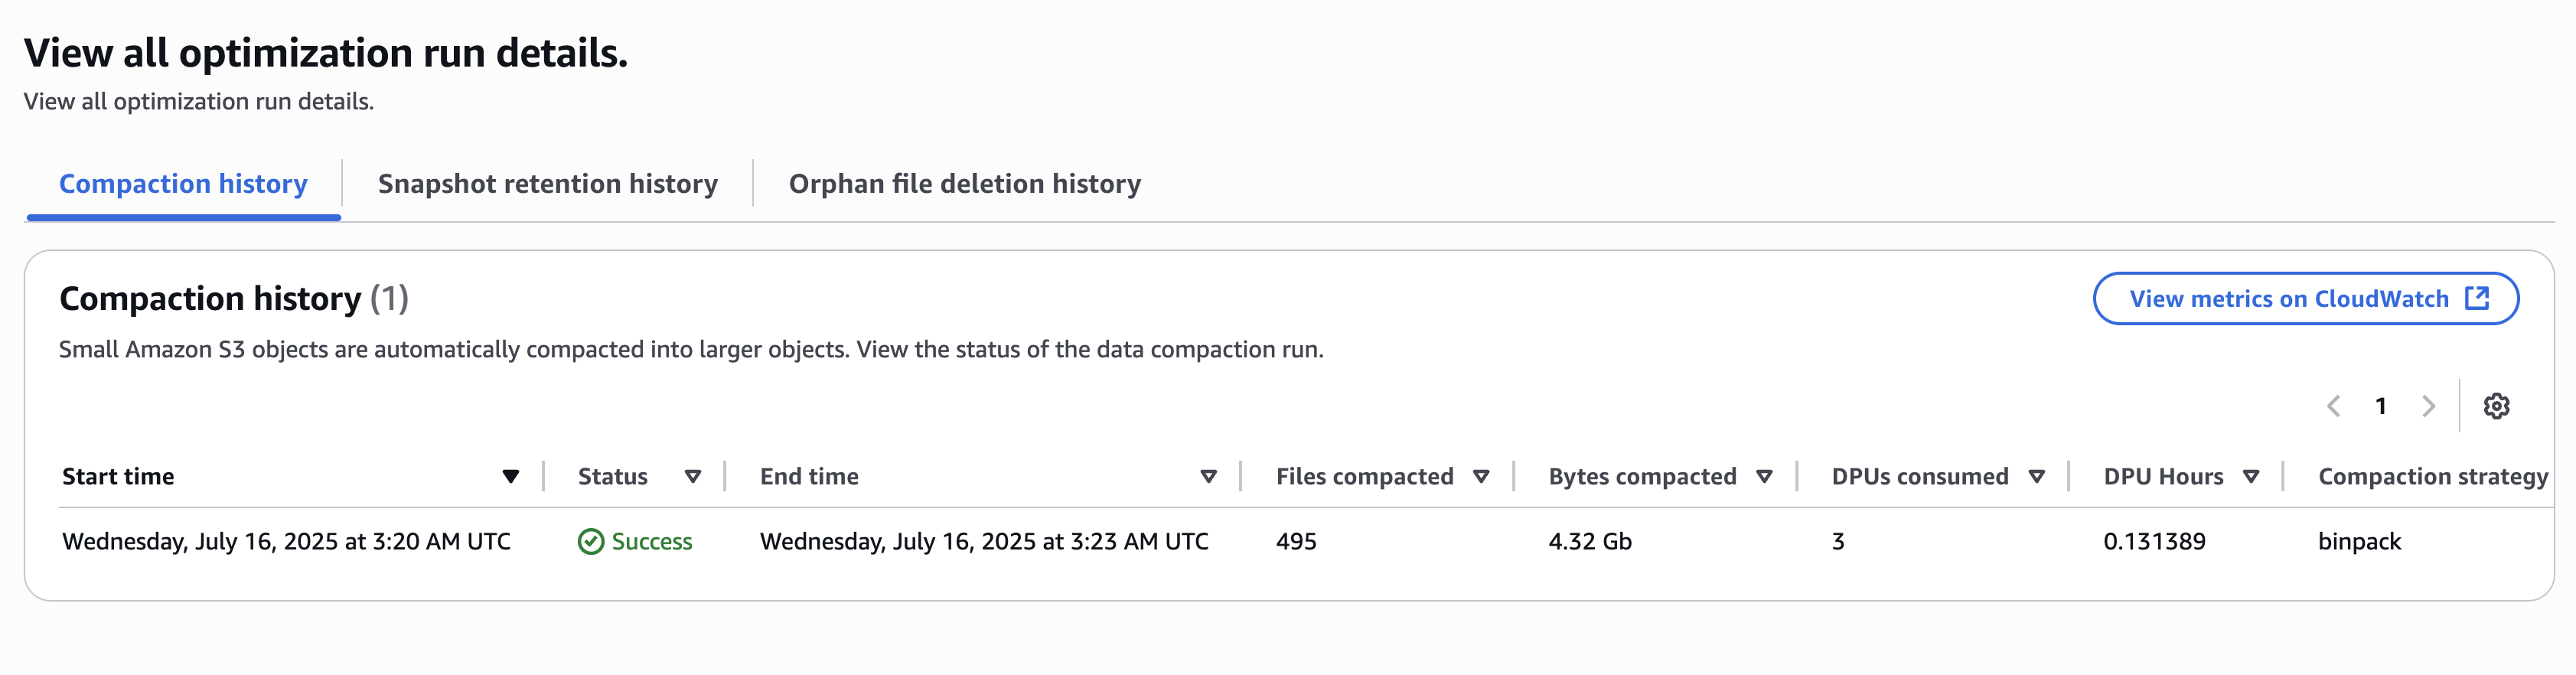
The catalog-level table optimizations for all databases and Iceberg tables are now enabled.
Customize setting of table optimizations at both the catalog and table-level
Although the catalog-level optimization applies common settings across all databases and Iceberg tables in your catalog, you might want to apply different strategies for specific Iceberg tables. You can use AWS Glue Data Catalog to enable both catalog-level and table-level optimizations based on specific table characteristics and access patterns. For example, in addition to configuring the catalog-level compaction with the bin-pack strategy for general-purpose Iceberg tables, you can apply the sort strategy at the table-level to tables with frequent range queries on timestamp columns.
This section shows configuring catalog-level and table-specific optimizations through a practical scenario. Imagine a real-time analytics table with frequent write operations that generates more orphan files due to constant metadata updates. Users also run selective queries filtering specific columns, which makes sort-order strategy preferable. Complete the following steps:
- Select another Iceberg table in the same catalog as before to configure the table-level optimizations on the AWS Lake Formation console. At this point, the catalog-level table optimizations are configured for this table.
- Choose Edit in Optimization configuration, as shown in the following screenshot.
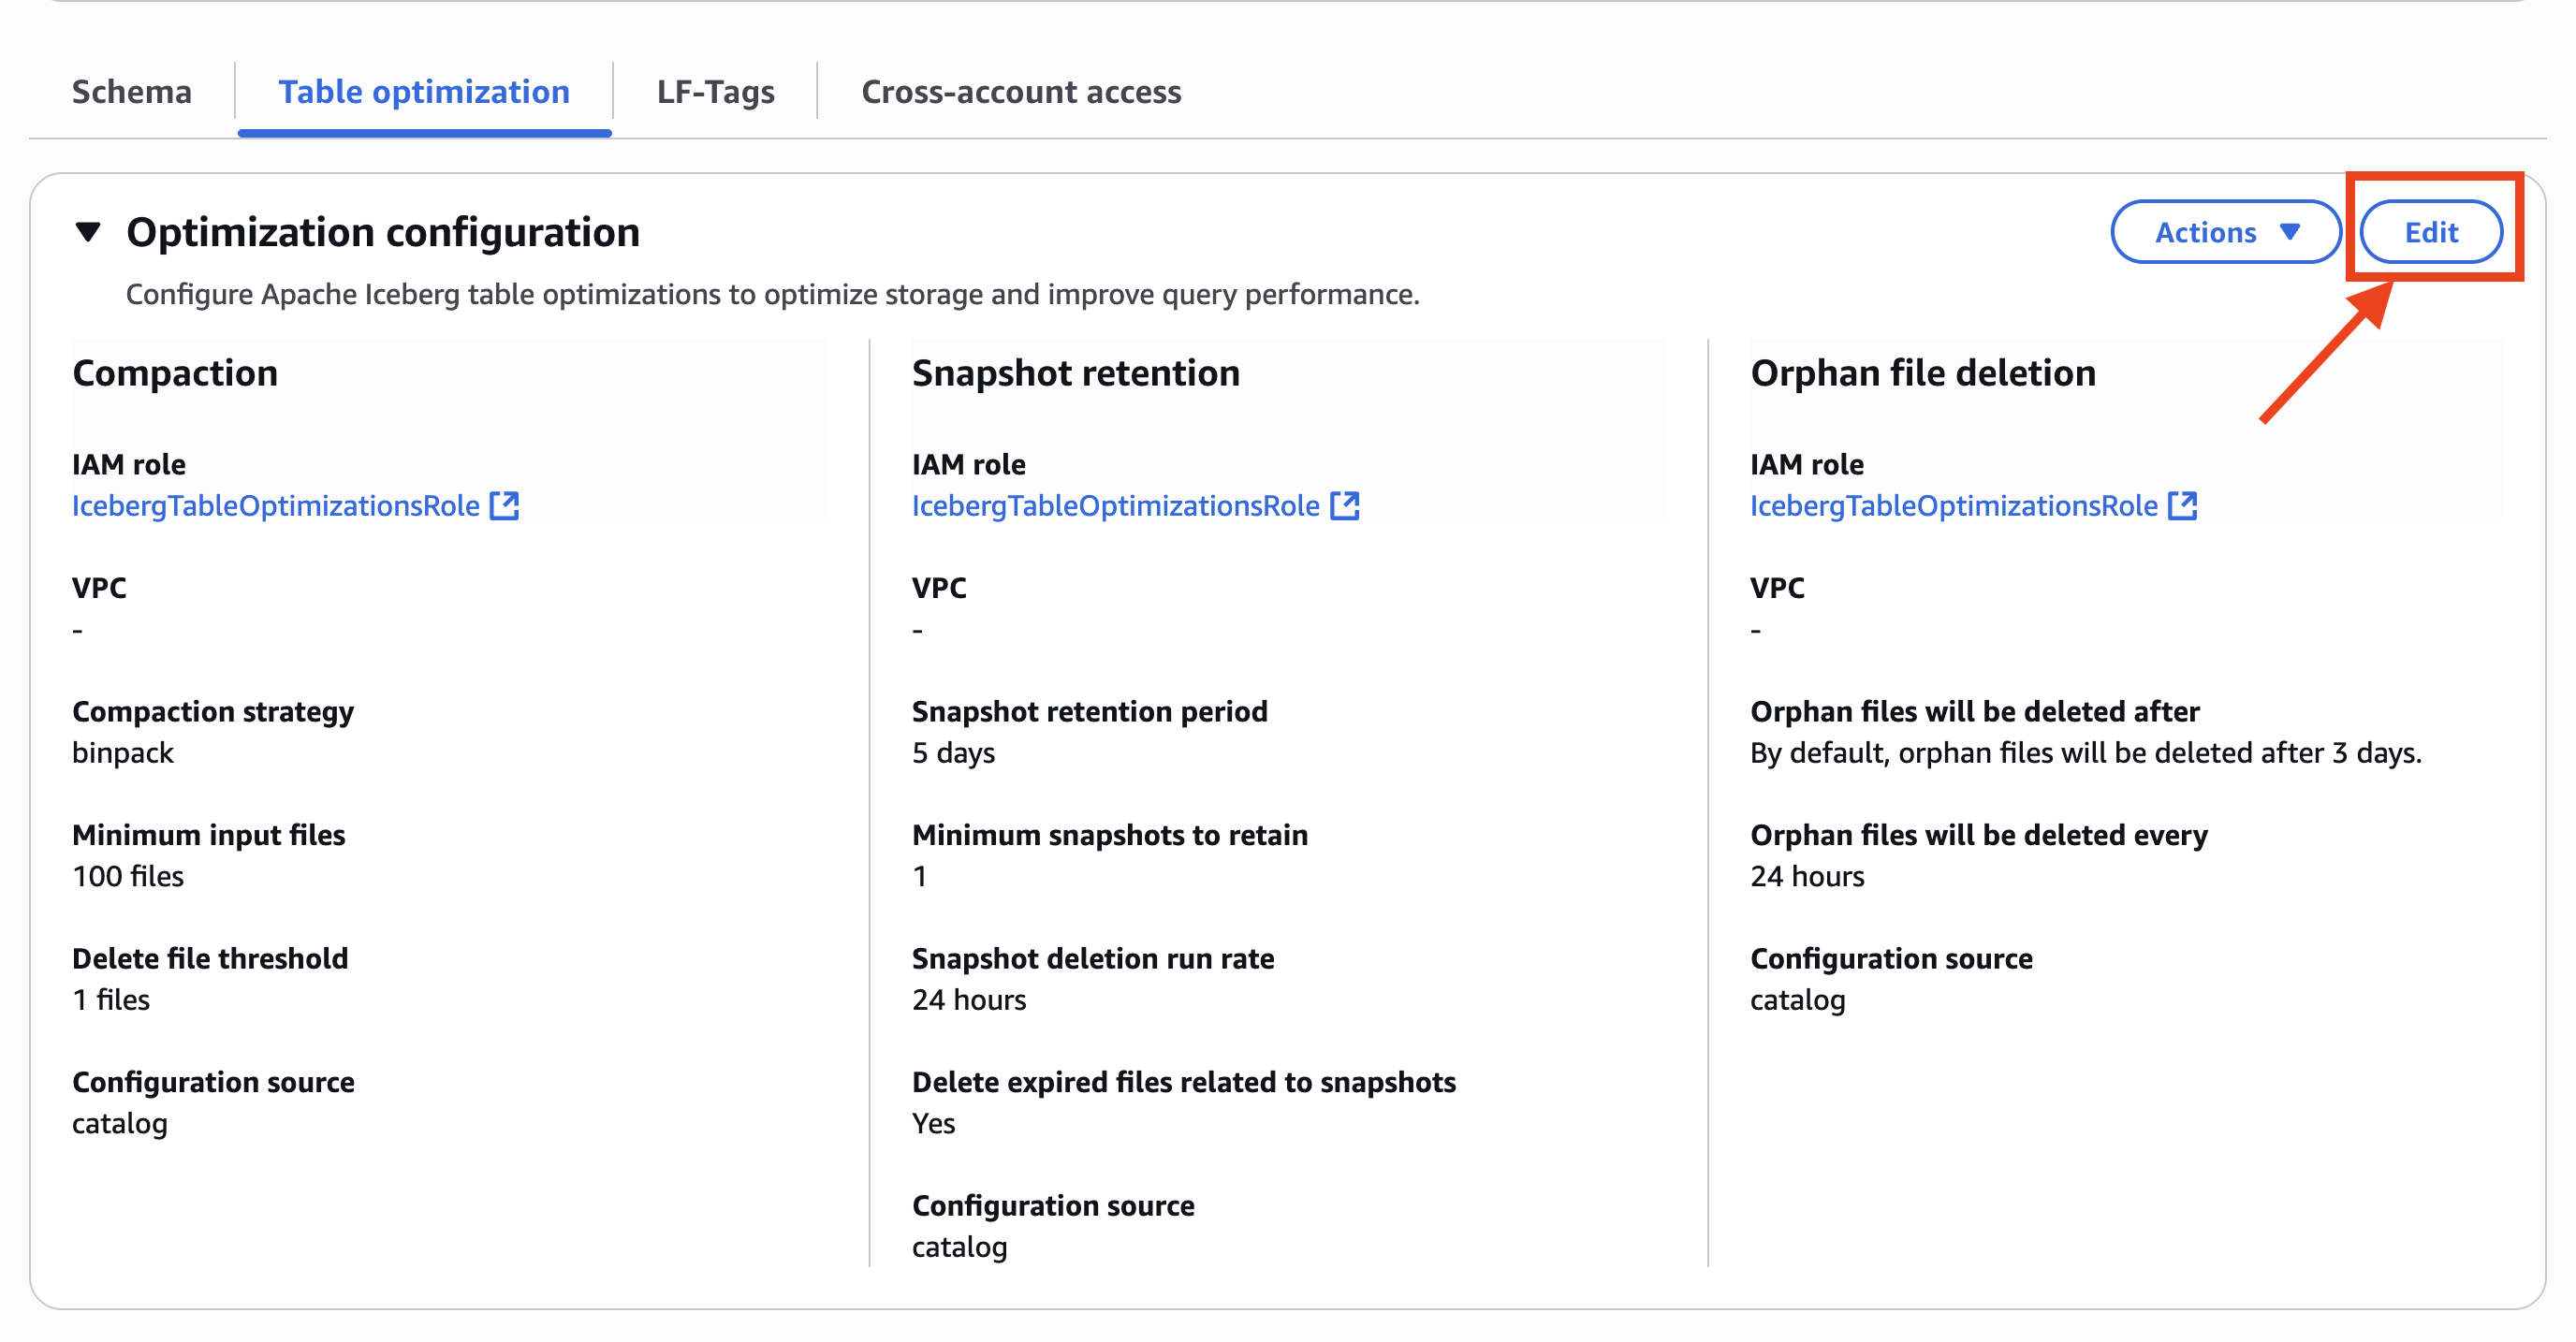
- In Optimization options, choose Compaction, Snapshot retention, and Orphan file deletion.
- In Optimization configuration, choose Customize settings.
- Select the same IAM role.
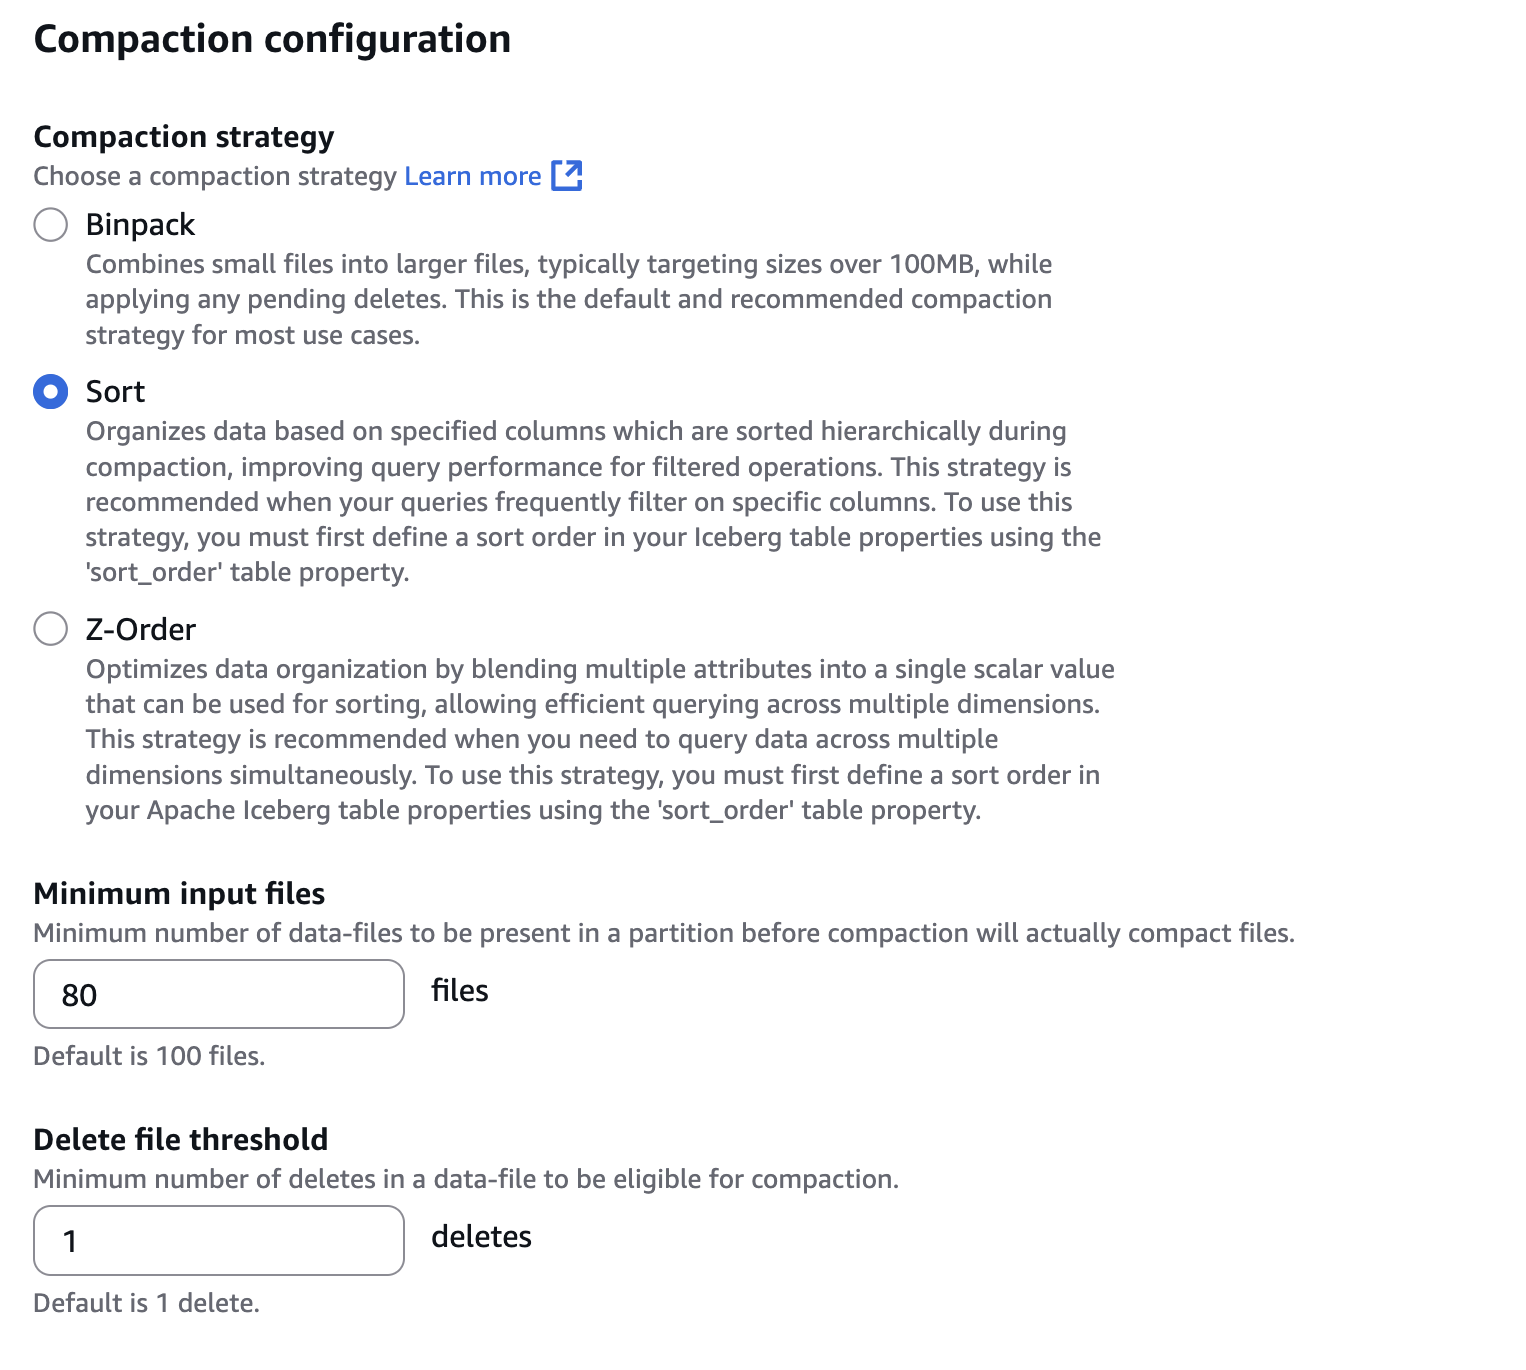
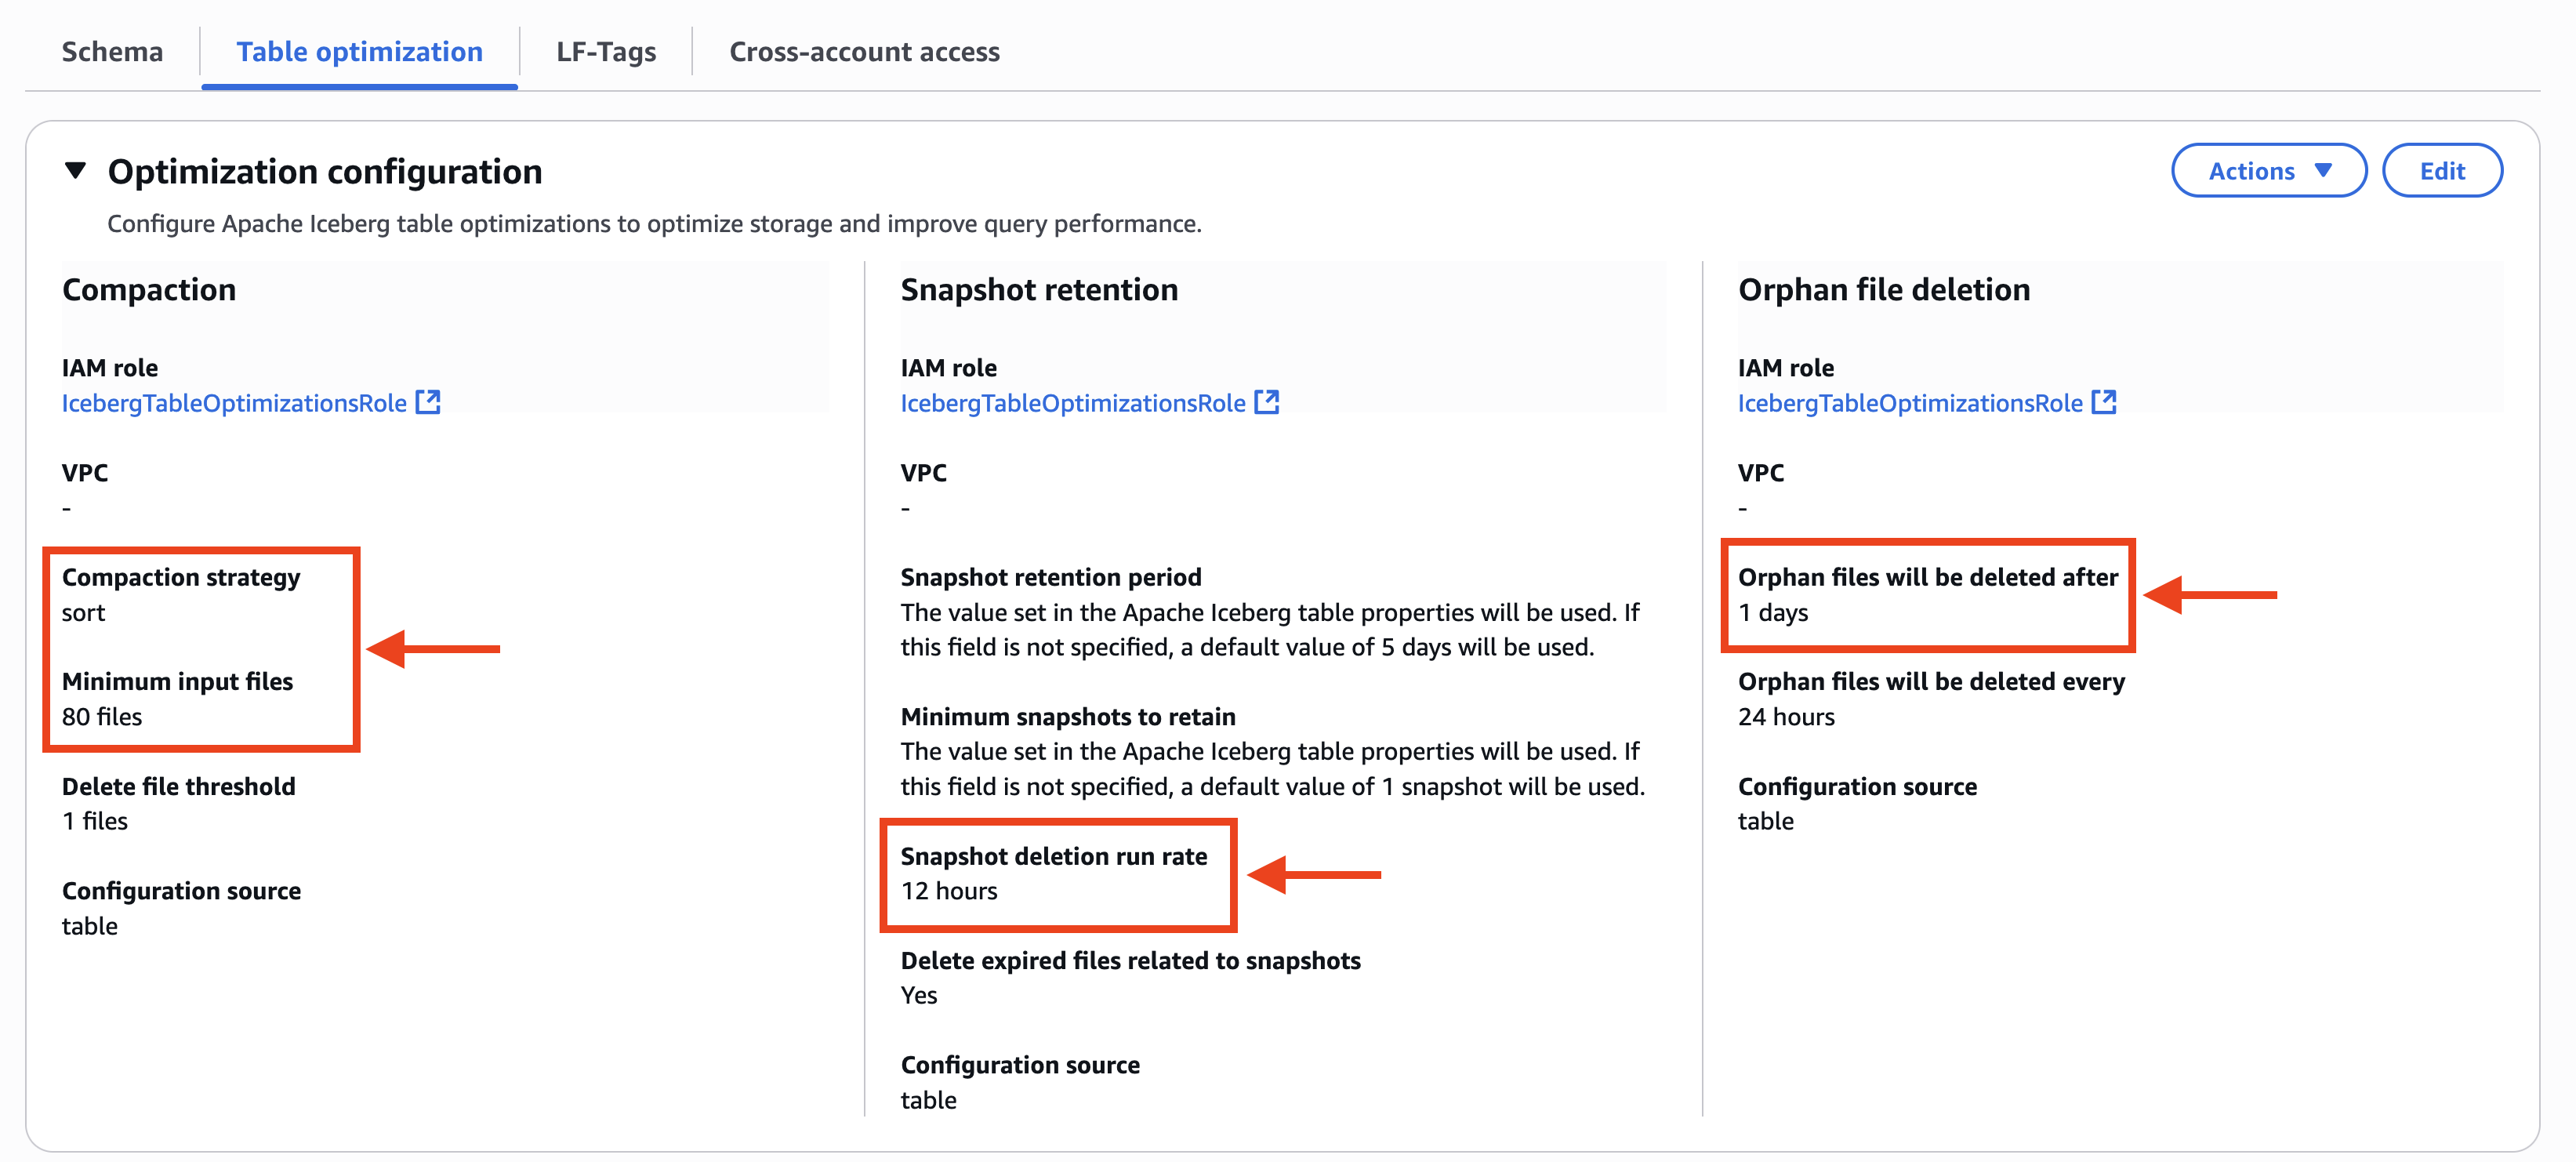
- In Compaction configuration, select Sort, as shown in the following screenshot. Also configure 80 files to Minimum input files, which is a threshold of the number of files to trigger the compaction. To configure Sort, a sort order needs to be defined in your Iceberg table. You can define the sort order with Spark SQL such as
ALTER TABLE db.tbl WRITE ORDERED BY <columns>.
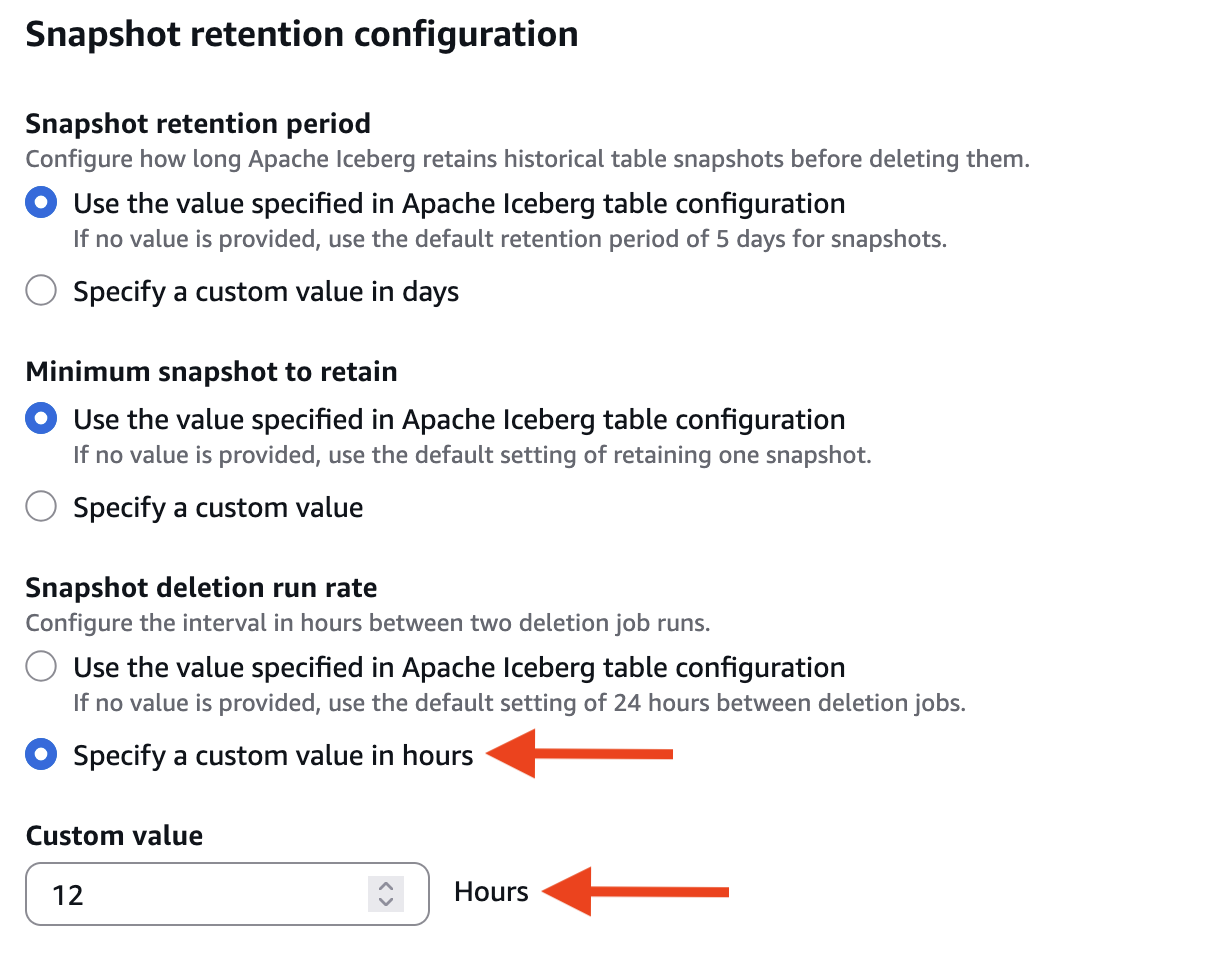
- In Snapshot retention configuration and Snapshot deletion run rate, select Specify a custom value in hours. Then, configure 12 hours to the interval between two deletion job runs, as shown in the following screenshot.
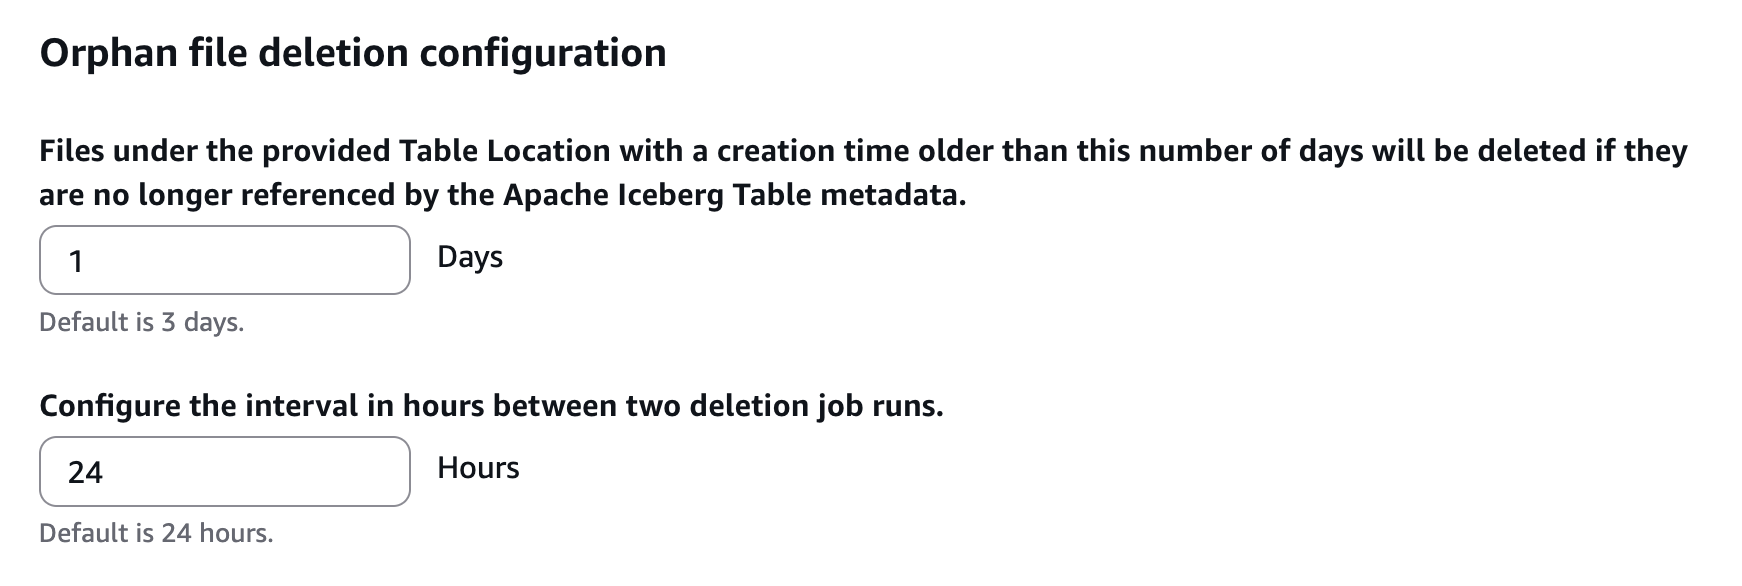
- In Orphan file deletion configuration, configure 1 day to Files under the provided Table Location with a creation time older than this number of days will be deleted if they are no longer referenced by the Apache Iceberg Table metadata.
- Choose Grant required permissions.
- Choose I acknowledge that expired data will be deleted as part of the optimizers.
- Choose Save.
- The Table optimization tab on the AWS Lake Formation console displays the custom setting of table optimizers. In Compaction, Compaction strategy is configured to sort and Minimum input files is also configured to 80 files. In Snapshot retention, Snapshot deletion run rate is configured to 12 hours. In Orphan file deletion, Orphan files will be deleted after is configured to 1 days, as shown in the following screenshot.
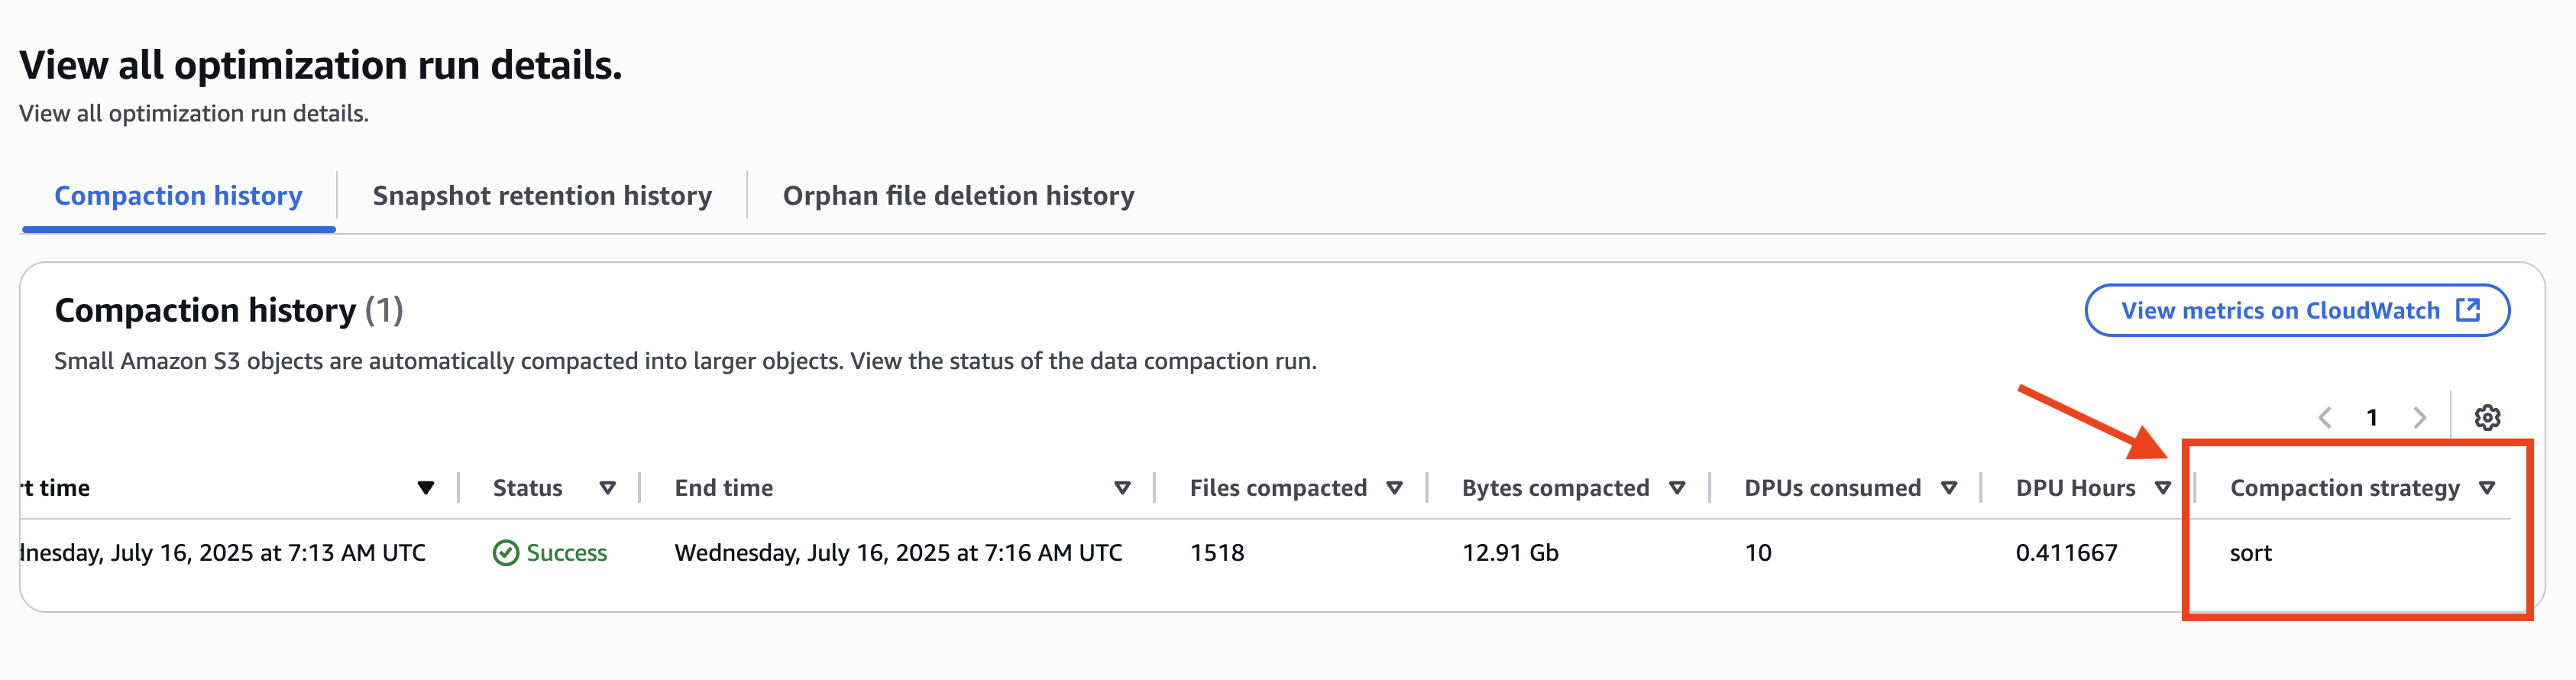
The compaction history shows sort as its table-level compaction strategy even if the strategy in the catalog-level is configured to binpack, as shown in the following screenshot.
In this scenario, the table-specific optimizations are configured along with the catalog-level optimizations. Combining the table and catalog-level optimizations means you can more flexibly manage your Iceberg table data deletions and compactions.
Conclusion
In this post, we demonstrated how to enable and manage using Amazon SageMaker lakehouse architecture with AWS Glue Data Catalog’s catalog-level table optimization feature for Iceberg tables. This enhancement significantly simplifies the management of Iceberg tables because you can enable automated maintenance operations across all tables with a single setting. Instead of configuring optimization settings for individual tables, you can now maintain your entire data lake more efficiently, reducing operational overhead while ensuring consistent optimization policies. We recommend enabling catalog-level table optimization to help you maintain a well-organized, high-performing, and cost-effective data lake while freeing up your teams to focus on deriving value from your data.
Try out this feature for your own use case and share your feedback and questions in the comments. To learn more about AWS Glue Data Catalog table optimizer, visit Optimizing Iceberg tables.
Acknowledgment: A special thanks to everyone who contributed to the development and launch of catalog level optimization: Siddharth Padmanabhan Ramanarayanan, Dhrithi Chidananda, Noella Jiang, Sangeet Lohariwala, Shyam Rathi, Anuj Jigneshkumar Vakil, and Jeremy Song.
About the authors
 Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services (AWS). He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.
 Noritaka Sekiyama is a Principal Big Data Architect with AWS Analytics services. He’s responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.
 Sandeep Adwankar is a Senior Product Manager at Amazon Web Services (AWS). Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products customers can use to improve how they manage, secure, and access data.
 Siddharth Padmanabhan Ramanarayanan is a Senior Software Engineer on the AWS Glue and AWS Lake Formation team, where he focuses on building scalable distributed systems for data analytics workloads. He is passionate about helping customers optimize their cloud infrastructure for performance and cost efficiency.
Some turbulence at CalyxOS
Post Syndicated from corbet original https://lwn.net/Articles/1033042/
CalyxOS is an Android distribution that
claims a focus on privacy and security. So when an
announcement from the project begins by saying “we want to assure
“, chances are that good things are
you that we have no reason to believe the security of CalyxOS and its
signing keys have been compromised
not happening.
In this case, it would appear that Nicholas Merrill, one of the founders of
the project, has left for unclear reasons, and CalyxOS is responding by
pausing all releases — and security updates — while its release process,
signing keys, and security protocols are reworked. The result will be no
updates for “four to six months
“. The project is recommending that
its users “should uninstall the OS
” and wait for an all-clear
signal. CalyxOS may have its work cut out for it when the time comes to
try to convince those users to come back.