Post Syndicated from xkcd.com original https://xkcd.com/2889/

Post Syndicated from xkcd.com original https://xkcd.com/2889/
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=64eugPFOcOo
Post Syndicated from Matthew Prince http://blog.cloudflare.com/author/matthew-prince/ original https://blog.cloudflare.com/thanksgiving-2023-security-incident
On Thanksgiving Day, November 23, 2023, Cloudflare detected a threat actor on our self-hosted Atlassian server. Our security team immediately began an investigation, cut off the threat actor’s access, and on Sunday, November 26, we brought in CrowdStrike’s Forensic team to perform their own independent analysis.
Yesterday, CrowdStrike completed its investigation, and we are publishing this blog post to talk about the details of this security incident.
We want to emphasize to our customers that no Cloudflare customer data or systems were impacted by this event. Because of our access controls, firewall rules, and use of hard security keys enforced using our own Zero Trust tools, the threat actor’s ability to move laterally was limited. No services were implicated, and no changes were made to our global network systems or configuration. This is the promise of a Zero Trust architecture: it’s like bulkheads in a ship where a compromise in one system is limited from compromising the whole organization.
From November 14 to 17, a threat actor did reconnaissance and then accessed our internal wiki (which uses Atlassian Confluence) and our bug database (Atlassian Jira). On November 20 and 21, we saw additional access indicating they may have come back to test access to ensure they had connectivity.
They then returned on November 22 and established persistent access to our Atlassian server using ScriptRunner for Jira, gained access to our source code management system (which uses Atlassian Bitbucket), and tried, unsuccessfully, to access a console server that had access to the data center that Cloudflare had not yet put into production in São Paulo, Brazil.
They did this by using one access token and three service account credentials that had been taken, and that we failed to rotate, after the Okta compromise of October 2023. All threat actor access and connections were terminated on November 24 and CrowdStrike has confirmed that the last evidence of threat activity was on November 24 at 10:44.
(Throughout this blog post all dates and times are UTC.)
Even though we understand the operational impact of the incident to be extremely limited, we took this incident very seriously because a threat actor had used stolen credentials to get access to our Atlassian server and accessed some documentation and a limited amount of source code. Based on our collaboration with colleagues in the industry and government, we believe that this attack was performed by a nation state attacker with the goal of obtaining persistent and widespread access to Cloudflare’s global network.
On November 24, after the threat actor was removed from our environment, our security team pulled in all the people they needed across the company to investigate the intrusion and ensure that the threat actor had been completely denied access to our systems, and to ensure we understood the full extent of what they accessed or tried to access.
Then, from November 27, we redirected the efforts of a large part of the Cloudflare technical staff (inside and outside the security team) to work on a single project dubbed “Code Red”. The focus was strengthening, validating, and remediating any control in our environment to ensure we are secure against future intrusion and to validate that the threat actor could not gain access to our environment. Additionally, we continued to investigate every system, account and log to make sure the threat actor did not have persistent access and that we fully understood what systems they had touched and which they had attempted to access.
CrowdStrike performed an independent assessment of the scope and extent of the threat actor’s activity, including a search for any evidence that they still persisted in our systems. CrowdStrike’s investigation provided helpful corroboration and support for our investigation, but did not bring to light any activities that we had missed. This blog post outlines in detail everything we and CrowdStrike uncovered about the activity of the threat actor.
The only production systems the threat actor could access using the stolen credentials was our Atlassian environment. Analyzing the wiki pages they accessed, bug database issues, and source code repositories, it appears they were looking for information about the architecture, security, and management of our global network; no doubt with an eye on gaining a deeper foothold. Because of that, we decided a huge effort was needed to further harden our security protocols to prevent the threat actor from being able to get that foothold had we overlooked something from our log files.
Our aim was to prevent the attacker from using the technical information about the operations of our network as a way to get back in. Even though we believed, and later confirmed, the attacker had limited access, we undertook a comprehensive effort to rotate every production credential (more than 5,000 individual credentials), physically segment test and staging systems, performed forensic triages on 4,893 systems, reimaged and rebooted every machine in our global network including all the systems the threat actor accessed and all Atlassian products (Jira, Confluence, and Bitbucket).
The threat actor also attempted to access a console server in our new, and not yet in production, data center in São Paulo. All attempts to gain access were unsuccessful. To ensure these systems are 100% secure, equipment in the Brazil data center was returned to the manufacturers. The manufacturers’ forensic teams examined all of our systems to ensure that no access or persistence was gained. Nothing was found, but we replaced the hardware anyway.
We also looked for software packages that hadn’t been updated, user accounts that might have been created, and unused active employee accounts; we went searching for secrets that might have been left in Jira tickets or source code, examined and deleted all HAR files uploaded to the wiki in case they contained tokens of any sort. Whenever in doubt, we assumed the worst and made changes to ensure anything the threat actor was able to access would no longer be in use and therefore no longer be valuable to them.
Every member of the team was encouraged to point out areas the threat actor might have touched, so we could examine log files and determine the extent of the threat actor’s access. By including such a large number of people across the company, we aimed to leave no stone unturned looking for evidence of access or changes that needed to be made to improve security.
The immediate “Code Red” effort ended on January 5, but work continues across the company around credential management, software hardening, vulnerability management, additional alerting, and more.
The attack started in October with the compromise of Okta, but the threat actor only began targeting our systems using those credentials from the Okta compromise in mid-November.
The following timeline shows the major events:
We’ve written about this before but, in summary, we were (for the second time) the victim of a compromise of Okta’s systems which resulted in a threat actor gaining access to a set of credentials. These credentials were meant to all be rotated.
Unfortunately, we failed to rotate one service token and three service accounts (out of thousands) of credentials that were leaked during the Okta compromise.
One was a Moveworks service token that granted remote access into our Atlassian system. The second credential was a service account used by the SaaS-based Smartsheet application that had administrative access to our Atlassian Jira instance, the third account was a Bitbucket service account which was used to access our source code management system, and the fourth was an AWS environment that had no access to the global network and no customer or sensitive data.
The one service token and three accounts were not rotated because mistakenly it was believed they were unused. This was incorrect and was how the threat actor first got into our systems and gained persistence to our Atlassian products. Note that this was in no way an error on the part of AWS, Moveworks or Smartsheet. These were merely credentials which we failed to rotate.
Our logs show that the threat actor started probing and performing reconnaissance of our systems beginning on November 14, looking for a way to use the credentials and what systems were accessible. They attempted to log into our Okta instance and were denied access. They attempted access to the Cloudflare Dashboard and were denied access.
Additionally, the threat actor accessed an AWS environment that is used to power the Cloudflare Apps marketplace. This environment was segmented with no access to global network or customer data. The service account to access this environment was revoked, and we validated the integrity of the environment.
The threat actor successfully accessed Atlassian Jira and Confluence on November 15 using the Moveworks service token to authenticate through our gateway, and then they used the Smartsheet service account to gain access to the Atlassian suite. The next day they began looking for information about the configuration and management of our global network, and accessed various Jira tickets.
The threat actor searched the wiki for things like remote access, secret, client-secret, openconnect, cloudflared, and token. They accessed 36 Jira tickets (out of a total of 2,059,357 tickets) and 202 wiki pages (out of a total of 194,100 pages).
The threat actor accessed Jira tickets about vulnerability management, secret rotation, MFA bypass, network access, and even our response to the Okta incident itself.
The wiki searches and pages accessed suggest the threat actor was very interested in all aspects of access to our systems: password resets, remote access, configuration, our use of Salt, but they did not target customer data or customer configurations.
The threat actor used the Smartsheet credential to create an Atlassian account that looked like a normal Cloudflare user. They added this user to a number of groups within Atlassian so that they’d have persistent access to the Atlassian environment should the Smartsheet service account be removed.
During this period, the attacker took a break from accessing our systems (apart from apparently briefly testing that they still had access) and returned just before Thanksgiving.
Since the Smartsheet service account had administrative access to Atlassian Jira, the threat actor was able to install the Sliver Adversary Emulation Framework, which is a widely used tool and framework that red teams and attackers use to enable “C2” (command and control), connectivity gaining persistent and stealthy access to a computer on which it is installed. Sliver was installed using the ScriptRunner for Jira plugin.
This allowed them continuous access to the Atlassian server, and they used this to attempt lateral movement. With this access the Threat Actor attempted to gain access to a non-production console server in our São Paulo, Brazil data center due to a non-enforced ACL. The access was denied, and they were not able to access any of the global network.
Over the next day, the threat actor viewed 120 code repositories (out of a total of 11,904 repositories). Of the 120, the threat actor used the Atlassian Bitbucket git archive feature on 76 repositories to download them to the Atlassian server, and even though we were not able to confirm whether or not they had been exfiltrated, we decided to treat them as having been exfiltrated.
The 76 source code repositories were almost all related to how backups work, how the global network is configured and managed, how identity works at Cloudflare, remote access, and our use of Terraform and Kubernetes. A small number of the repositories contained encrypted secrets which were rotated immediately even though they were strongly encrypted themselves.
We focused particularly on these 76 source code repositories to look for embedded secrets, (secrets stored in the code were rotated), vulnerabilities and ways in which an attacker could use them to mount a subsequent attack. This work was done as a priority by engineering teams across the company as part of “Code Red”.
As a SaaS company, we’ve long believed that our source code itself is not as precious as the source code of software companies that distribute software to end users. In fact, we’ve open sourced a large amount of our source code and speak openly through our blog about algorithms and techniques we use. So our focus was not on someone having access to the source code, but whether that source code contained embedded secrets (such as a key or token) and vulnerabilities.
Our security team was alerted to the threat actor’s presence at 16:00 and deactivated the Smartsheet service account 35 minutes later. 48 minutes later the user account created by the threat actor was found and deactivated. Here’s the detailed timeline for the major actions taken to block the threat actor once the first alert was raised.
15:58 – The threat actor adds the Smartsheet service account to an administrator group.
16:00 – Automated alert about the change at 15:58 to our security team.
16:12 – Cloudflare SOC starts investigating the alert.
16:35 – Smartsheet service account deactivated by Cloudflare SOC.
17:23 – The threat actor-created Atlassian user account is found and deactivated.
17:43 – Internal Cloudflare incident declared.
21:31 – Firewall rules put in place to block the threat actor’s known IP addresses.
10:44 – Last known threat actor activity.
11:59 – Sliver removed.
Throughout this timeline, the threat actor tried to access a myriad of other systems at Cloudflare but failed because of our access controls, firewall rules, and use of hard security keys enforced using our own Zero Trust tools.
To be clear, we saw no evidence whatsoever that the threat actor got access to our global network, data centers, SSL keys, customer databases or configuration information, Cloudflare Workers deployed by us or customers, AI models, network infrastructure, or any of our datastores like Workers KV, R2 or Quicksilver. Their access was limited to the Atlassian suite and the server on which our Atlassian runs.
A large part of our “Code Red” effort was understanding what the threat actor got access to and what they tried to access. By looking at logging across systems we were able to track attempted access to our internal metrics, network configuration, build system, alerting systems, and release management system. Based on our review, none of their attempts to access these systems were successful. Independently, CrowdStrike performed an assessment of the scope and extent of the threat actor’s activity, which did not bring to light activities that we had missed and concluded that the last evidence of threat activity was on November 24 at 10:44.
We are confident that between our investigation and CrowdStrike’s, we fully understand the threat actor’s actions and that they were limited to the systems on which we saw their activity.
This was a security incident involving a sophisticated actor, likely a nation-state, who operated in a thoughtful and methodical manner. The efforts we have taken to ensure that the ongoing impact of the incident was limited and that we are well-prepared to fend off any sophisticated attacks in the future. This required the efforts of a significant number of Cloudflare’s engineering staff, and, for over a month, this was the highest priority at Cloudflare. The entire Cloudflare team worked to ensure that our systems were secure, the threat actor’s access was understood, to remediate immediate priorities (such as mass credential rotation), and to build a plan of long-running work to improve our overall security based on areas for improvement discovered during this process.
I am incredibly grateful to everyone at Cloudflare who responded quickly over the Thanksgiving holiday to conduct an initial analysis and lock out of the threat actor and all those who contributed to this effort. It would be impossible to name everyone involved, but their long hours and dedicated work made it possible to undertake an essential review and change of Cloudflare’s security while keeping our global network running and our customers’ service running.
We are grateful to CrowdStrike for having been available immediately to conduct an independent assessment. Now that their final report is complete, we are confident in our internal analysis and remediation of the intrusion and are making this blog post available.
IOCs
Below are the Indications of Compromise (IOCs) that we saw from this threat actor. We are publishing them so that other organizations, and especially those that may have been impacted by the Okta breach, can search their logs to confirm the same threat actor did not access their systems.
| Indicator | Indicator Type | SHA256 | Description |
|---|---|---|---|
| 193.142.58[.]126 | IPv4 | N/A | Primary threat actor Infrastructure, owned by M247 Europe SRL (Bucharest, Romania |
| 198.244.174[.]214 | IPv4 | N/A | Sliver C2 server, owned by OVH SAS (London, England) |
| idowall[.]com | Domain | N/A | Infrastructure serving Sliver payload |
| jvm-agent | Filename | bdd1a085d651082ad567b03e5186d1d4 6d822bb7794157ab8cce95d850a3caaf |
Sliver payload |
Post Syndicated from Satesh Sonti original https://aws.amazon.com/blogs/big-data/combine-transactional-streaming-and-third-party-data-on-amazon-redshift-for-financial-services/
Financial services customers are using data from different sources that originate at different frequencies, which includes real time, batch, and archived datasets. Additionally, they need streaming architectures to handle growing trade volumes, market volatility, and regulatory demands. The following are some of the key business use cases that highlight this need:
The challenge is to come up with a solution that can handle these disparate sources, varied frequencies, and low-latency consumption requirements. The solution should be scalable, cost-efficient, and straightforward to adopt and operate. Amazon Redshift features like streaming ingestion, Amazon Aurora zero-ETL integration, and data sharing with AWS Data Exchange enable near-real-time processing for trade reporting, risk management, and trade optimization.
In this post, we provide a solution architecture that describes how you can process data from three different types of sources—streaming, transactional, and third-party reference data—and aggregate them in Amazon Redshift for business intelligence (BI) reporting.
This solution architecture is created prioritizing a low-code/no-code approach with the following guiding principles:
The following diagram illustrates the solution architecture and how these guiding principles were applied to the ingestion, aggregation, and reporting components.

You can use the following AWS CloudFormation template to deploy the solution.

This stack creates the following resources and necessary permissions to integrate the services:
To ingest data, you use Amazon Redshift Streaming Ingestion to load streaming data from the Kinesis data stream. For transactional data, you use the Redshift zero-ETL integration with Amazon Aurora MySQL. For third-party reference data, you take advantage of AWS Data Exchange data shares. These capabilities allow you to quickly build scalable data pipelines because you can increase the capacity of Kinesis Data Streams shards, compute for zero-ETL sources and targets, and Redshift compute for data shares when your data grows. Redshift streaming ingestion and zero-ETL integration are low-code/no-code solutions that you can build with simple SQLs without investing significant time and money into developing complex custom code.
For the data used to create this solution, we partnered with FactSet, a leading financial data, analytics, and open technology provider. FactSet has several datasets available in the AWS Data Exchange marketplace, which we used for reference data. We also used FactSet’s market data solutions for historical and streaming market quotes and trades.
Data is processed in Amazon Redshift adhering to an extract, load, and transform (ELT) methodology. With virtually unlimited scale and workload isolation, ELT is more suited for cloud data warehouse solutions.
You use Redshift streaming ingestion for real-time ingestion of streaming quotes (bid/ask) from the Kinesis data stream directly into a streaming materialized view and process the data in the next step using PartiQL for parsing the data stream inputs. Note that streaming materialized views differs from regular materialized views in terms of how auto refresh works and the data management SQL commands used. Refer to Streaming ingestion considerations for details.
You use the zero-ETL Aurora integration for ingesting transactional data (trades) from OLTP sources. Refer to Working with zero-ETL integrations for currently supported sources. You can combine data from all these sources using views, and use stored procedures to implement business transformation rules like calculating weighted averages across sectors and exchanges.
Historical trade and quote data volumes are huge and often not queried frequently. You can use Amazon Redshift Spectrum to access this data in place without loading it into Amazon Redshift. You create external tables pointing to data in Amazon Simple Storage Service (Amazon S3) and query similarly to how you query any other local table in Amazon Redshift. Multiple Redshift data warehouses can concurrently query the same datasets in Amazon S3 without the need to make copies of the data for each data warehouse. This feature simplifies accessing external data without writing complex ETL processes and enhances the ease of use of the overall solution.
Let’s review a few sample queries used for analyzing quotes and trades. We use the following tables in the sample queries:
You can use the following query to find weighted average spreads on quotes:
You can use the following query to find $-volume on trades by detailed exchange, by sector, and by major exchange (NYSE and Nasdaq):
You can use Amazon QuickSight and Amazon Managed Grafana for BI and real-time reporting, respectively. These services natively integrate with Amazon Redshift without the need to use additional connectors or software in between.
You can run a direct query from QuickSight for BI reporting and dashboards. With QuickSight, you can also locally store data in the SPICE cache with auto refresh for low latency. Refer to Authorizing connections from Amazon QuickSight to Amazon Redshift clusters for comprehensive details on how to integrate QuickSight with Amazon Redshift.
You can use Amazon Managed Grafana for near-real-time trade dashboards that are refreshed every few seconds. The real-time dashboards for monitoring the trade ingestion latencies are created using Grafana and the data is sourced from system views in Amazon Redshift. Refer to Using the Amazon Redshift data source to learn about how to configure Amazon Redshift as a data source for Grafana.
The users who interact with regulatory reporting systems include analysts, risk managers, operators, and other personas that support business and technology operations. Apart from generating regulatory reports, these teams require visibility into the health of the reporting systems.
In this section, we explore some examples of historical quotes analysis from the Amazon QuickSight dashboard.
The following chart shows the daily aggregation by sector of the weighted average bid-ask spreads of all the individual trades on NASDAQ and NYSE for 3 months. To calculate the average daily spread, each spread is weighted by the sum of the bid and the ask dollar volume. The query to generate this chart processes 103 billion of data points in total, joins each trade with the sector reference table, and runs in less than 10 seconds.

The following chart shows the daily aggregation of the weighted average bid-ask spreads of all the individual trades on NASDAQ and NYSE for 3 months. The calculation methodology and query performance metrics are similar to those of the preceding chart.

In this section, we explore some examples of historical trades analysis from the Amazon QuickSight dashboard.
The following chart shows the daily aggregation by sector of all the individual trades on NASDAQ and NYSE for 3 months. The query to generate this chart processes 3.6 billion of trades in total, joins each trade with the sector reference table, and runs in under 5 seconds.

The following chart shows the daily aggregation by exchange group of all the individual trades for 3 months. The query to generate this chart has similar performance metrics as the preceding chart.

Monitoring and observability is an important requirement for any critical business application such as trade reporting, risk management, and trade management systems. Apart from system-level metrics, it’s also important to monitor key performance indicators in real time so that operators can be alerted and respond as soon as possible to business-impacting events. For this demonstration, we have built dashboards in Grafana that monitor the delay of quote and trade data from the Kinesis data stream and Aurora, respectively.
The quote ingestion delay dashboard shows the amount of time it takes for each quote record to be ingested from the data stream and be available for querying in Amazon Redshift.

The trade ingestion delay dashboard shows the amount of time it takes for a transaction in Aurora to become available in Amazon Redshift for querying.

To clean up your resources, delete the stack you deployed using AWS CloudFormation. For instructions, refer to Deleting a stack on the AWS CloudFormation console.
Increasing volumes of trading activity, more complex risk management, and enhanced regulatory requirements are leading capital markets firms to embrace real-time and near-real-time data processing, even in mid- and back-office platforms where end of day and overnight processing was the standard. In this post, we demonstrated how you can use Amazon Redshift capabilities for ease of use, low maintenance, and cost-efficiency. We also discussed cross-service integrations to ingest streaming market data, process updates from OLTP databases, and use third-party reference data without having to perform complex and expensive ETL or ELT processing before making the data available for analysis and reporting.
Please reach out to us if you need any guidance in implementing this solution. Refer to Real-time analytics with Amazon Redshift streaming ingestion, Getting started guide for near-real time operational analytics using Amazon Aurora zero-ETL integration with Amazon Redshift, and Working with AWS Data Exchange data shares as a producer for more information.
 Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 18 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.
 Alket Memushaj works as a Principal Architect in the Financial Services Market Development team at AWS. Alket is responsible for technical strategy for capital markets, working with partners and customers to deploy applications across the trade lifecycle to the AWS Cloud, including market connectivity, trading systems, and pre- and post-trade analytics and research platforms.
 Ruben Falk is a Capital Markets Specialist focused on AI and data & analytics. Ruben consults with capital markets participants on modern data architecture and systematic investment processes. He joined AWS from S&P Global Market Intelligence where he was Global Head of Investment Management Solutions.
 Jeff Wilson is a World-wide Go-to-market Specialist with 15 years of experience working with analytic platforms. His current focus is sharing the benefits of using Amazon Redshift, Amazon’s native cloud data warehouse. Jeff is based in Florida and has been with AWS since 2019.
Post Syndicated from Shijian Tang original https://aws.amazon.com/blogs/big-data/preprocess-and-fine-tune-llms-quickly-and-cost-effectively-using-amazon-emr-serverless-and-amazon-sagemaker/
Large language models (LLMs) are becoming increasing popular, with new use cases constantly being explored. In general, you can build applications powered by LLMs by incorporating prompt engineering into your code. However, there are cases where prompting an existing LLM falls short. This is where model fine-tuning can help. Prompt engineering is about guiding the model’s output by crafting input prompts, whereas fine-tuning is about training the model on custom datasets to make it better suited for specific tasks or domains.
Before you can fine-tune a model, you need to find a task-specific dataset. One dataset that is commonly used is the Common Crawl dataset. The Common Crawl corpus contains petabytes of data, regularly collected since 2008, and contains raw webpage data, metadata extracts, and text extracts. In addition to determining which dataset should be used, cleansing and processing the data to the fine-tuning’s specific need is required.
We recently worked with a customer who wanted to preprocess a subset of the latest Common Crawl dataset and then fine-tune their LLM with cleaned data. The customer was looking for how they could achieve this in the most cost-effective way on AWS. After discussing the requirements, we recommended using Amazon EMR Serverless as their platform for data preprocessing. EMR Serverless is well suited for large-scale data processing and eliminates the need for infrastructure maintenance. In terms of cost, it only charges based on the resources and duration used for each job. The customer was able to preprocess hundreds of TBs of data within a week using EMR Serverless. After they preprocessed the data, they used Amazon SageMaker to fine-tune the LLM.
In this post, we walk you through the customer’s use case and architecture used.
In the following sections, we first introduce the Common Crawl dataset and how to explore and filter the data we need. Amazon Athena only charges for the data size it scans and is used to explore and filter the data quickly, while being cost-effective. EMR Serverless provides a cost-efficient and no-maintenance option for Spark data processing, and is used to process the filtered data. Next, we use Amazon SageMaker JumpStart to fine-tune the Llama 2 model with the preprocessed dataset. SageMaker JumpStart provides a set of solutions for the most common use cases that can be deployed with just a few clicks. You don’t need to write any code to fine-tune an LLM such as Llama 2. Finally, we deploy the fine-tuned model using Amazon SageMaker and compare the differences in text output for the same question between the original and fine-tuned Llama 2 models.
The following diagram illustrates the architecture of this solution.

Before you dive deep into the solution details, complete the following prerequisite steps:
Common Crawl is an open corpus dataset obtained by crawling over 50 billion webpages. It includes massive amounts of unstructured data in multiple languages, starting from 2008 and reaching the petabyte level. It is continuously updated.
In the training of GPT-3, the Common Crawl dataset accounts for 60% of its training data, as shown in the following diagram (source: Language Models are Few-Shot Learners).

Another important dataset worth mentioning is the C4 dataset. C4, short for Colossal Clean Crawled Corpus, is a dataset derived from postprocessing the Common Crawl dataset. In Meta’s LLaMA paper, they outlined the datasets used, with Common Crawl accounting for 67% (utilizing 3.3 TB of data) and C4 for 15% (utilizing 783 GB of data). The paper emphasizes the significance of incorporating differently preprocessed data for enhancing model performance. Despite the original C4 data being part of Common Crawl, Meta opted for the reprocessed version of this data.
In this section, we cover common ways to interact, filter, and process the Common Crawl dataset.
The Common Crawl raw dataset includes three types of data files: raw webpage data (WARC), metadata (WAT), and text extraction (WET).
Data collected after 2013 is stored in WARC format and includes corresponding metadata (WAT) and text extraction data (WET). The dataset is located in Amazon S3, updated on a monthly basis, and can be accessed directly through AWS Marketplace.
For example, the following snippet is data from June of 2023:
The Common Crawl dataset also provides an index table for filtering data, which is called cc-index-table.
The cc-index-table is an index of the existing data, providing a table-based index of WARC files. It allows for easy lookup of information, such as which WARC file corresponds to a specific URL.
The Common Crawl GitHub repo provides corresponding Athena statements to query the index. For explanations of each field, refer to Common Crawl Index Athena.
For example, you can create an Athena table to map cc-index data with the following code:
Post Syndicated from Molly Clancy original https://www.backblaze.com/blog/whats-diff-ram-vs-storage/
Memory is a finite resource when it comes to both humans and computers—it’s one of the most common causes of computer issues. And if you’ve ever left the house without your keys, you know memory is one of the most common human problems, too.
If you’re unclear about the different types of memory in your computer, it makes pinpointing the cause of computer problems that much harder. You might hear folks use the terms memory and storage interchangeably, but there are some important differences. Understanding how both components work can help you understand what kind of computer you need, diagnose problems you’re having, and know when it’s time to consider upgrades.
Random access memory (RAM) and storage are both forms of computer memory, but they serve different functions.
RAM is volatile memory used by the computer’s processor to store and quickly access data that is actively being used or processed. Volatile memory maintains data only while the device is powered on. RAM takes the form of computer chips—integrated circuits—that are either soldered directly onto the main logic board of your computer or installed in memory modules that go in sockets on your computer’s logic board.
You can think of it like a desk—it’s where your computer gets work done. When you double-click on an app, open a document, or do much of anything, part of your “desk” is covered and can’t be used by anything else. As you open more files, it is like covering your desk with more and more items. Using a desk with a handful of files is easy, but a desk that is covered with a bunch of stuff gets difficult to use.
On the other hand, storage is used for long-term data retention, like a hard disk drive (HDD) or solid state drive (SSD). Compared with RAM, this type of storage is non-volatile, which means it retains information even when a device is powered off. You can think of storage like a filing cabinet—a place next to your desk where you can retrieve information as needed.
Two of the primary differences between RAM and storage are speed and performance. RAM is significantly faster than storage. Data stored in RAM can be written and accessed almost instantly, so it’s very fast—milliseconds fast. DDR4 RAM, one of the newer types of RAM technology, is capable of a peak transfer rate of 25.6GB/s! RAM has a very fast path to the computer’s central processing unit (CPU), the brain of the computer that does most of the work.
Storage, as it’s slower in comparison, is responsible for holding the operating system (OS), applications, and user data for the long term—it should still be fast, but it doesn’t need to be as fast as RAM.
That said, computer storage is getting faster thanks to the popularity of SSDs. SSDs are much faster than hard drives since they use integrated circuits instead of mechanical platters that have to be read sequentially, like HDDs. SSDs use a special type of memory circuitry called non-volatile RAM (NVRAM) to store data, so those shorter term memory access points stay in place even when the computer is turned off.
Even though SSDs are faster than HDDs, they’re still slower than RAM. There are two reasons for that difference in speed. First, the memory chips in SSDs are slower than those in RAM. Second, there is a bottleneck created by the interface that connects the storage device to the computer. RAM, in comparison, has a much faster interface.
RAM is typically smaller in capacity compared to storage. It is measured in gigabytes (GB) or terabytes (TB), whereas storage capacities can reach multiple terabytes or even petabytes. The smaller size of RAM is intentional, as it is designed to store only the data currently in use, ensuring quick access for the processor.
Another key difference is the volatility of RAM and the persistence of storage. RAM is volatile, meaning it loses its data when the power is turned off or the system is rebooted. This makes it ideal for quick data access and manipulation, but unsuitable for long-term storage. Storage is non-volatile or persistent, meaning it retains data even when the power is off, making it suitable for holding files, applications, and the operating system over extended periods.
Understanding how much RAM you have might be one of your first steps for diagnosing computer performance issues.
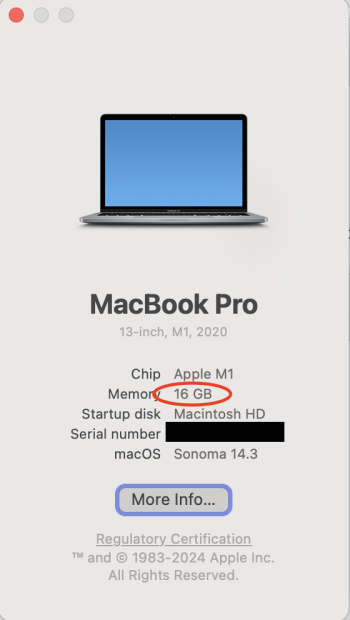
Use the following steps to confirm how much RAM your computer has installed. We’ll start with an Apple computer. Click on the Apple menu and then click About This Mac. In the screenshot below, we can see that the computer has 16GB of RAM.
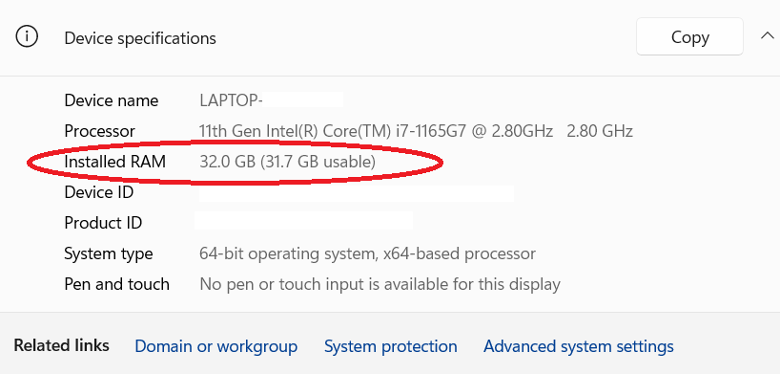
With a Windows 11 computer, use the following steps to see how much RAM you have installed. Open the Control Panel by clicking the Windows button and typing “control panel,” then click System and Security, and then click System. Look for the line “Installed RAM.” In the screenshot below, you can see that the computer has 32GB of RAM installed.
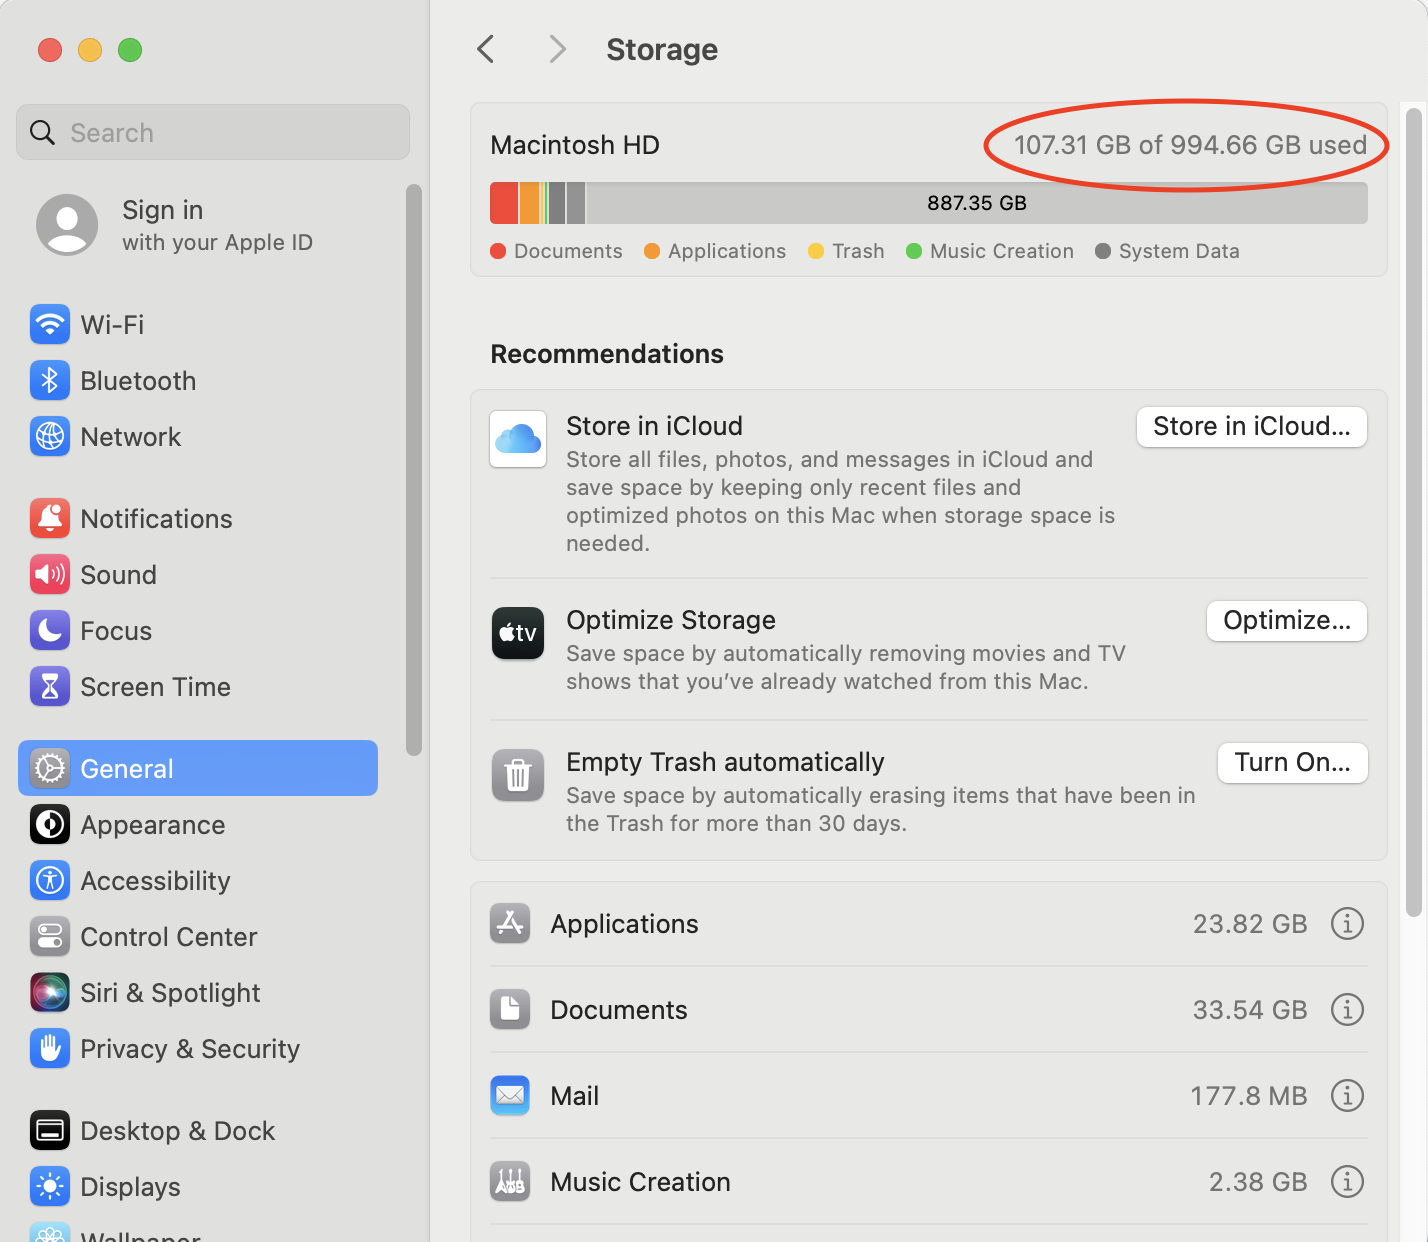
To view how much free storage space you have available on a Mac computer, use these steps. Click on the Apple menu, then System Settings, select General, and then open Storage. In the screenshot below, we’ve circled where your available storage is displayed.
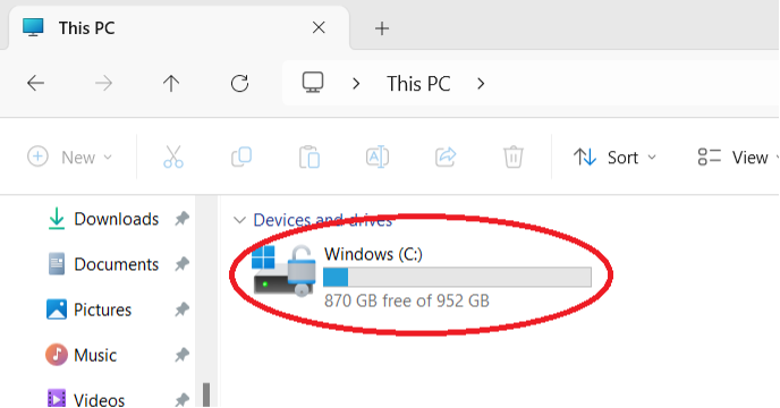
With a Windows 11 computer, it is also easy to view how much available storage space you have. Click the Windows button and type in “file explorer.” When File Explorer opens, click on This PC from the list of options in the left-hand pane. In the screenshot below, we’ve circled where your available storage is displayed (in this case, 200GB).
For most general-purpose uses of computers—email, writing documents, surfing the web, or watching Netflix—the RAM that comes with our computer is enough. If you own your computer for a long enough time, you might need to add a bit more to keep up with memory demands from newer apps and OSes. Specifically, more RAM makes it possible for you to use more apps, documents, and larger files at the same time.
People that work with very large files like large databases, videos, and images can benefit significantly from having more RAM. If you regularly use large files, it is worth checking to see if your computer’s RAM is upgradeable.
In some situations, adding more RAM is worth the expense. For example, editing videos and high-resolution images takes a lot of memory. In addition, high-end audio recording and editing as well as some scientific work require significant RAM.
However, not all computers allow you to upgrade RAM. For example, the Chromebook typically has a fixed amount of RAM, and you cannot install more. So, when you’re buying a new computer—particularly if you plan on using that computer for more than five years, make sure to 1) understand how much RAM your computer has, and, 2) if you can upgrade the computer’s RAM.
When your computer’s RAM is filled up, your computer has to get creative to keep working. Specifically, your computer starts to temporarily use your hard drive or SSD as “virtual memory.” If you have relatively fast storage like an SSD, virtual memory will be fast. On the other hand, using a traditional hard drive will be fairly slow.
Besides RAM, the most serious bottleneck to improving performance in your computer can be your storage. Even with plenty of RAM installed, computers need to read and write information from the storage system (i.e., the HDD or the SSD).
Hard drives come in different speeds and sizes. For laptops and desktops, the most common RPM rates are between 5400–7200RPM. In some cases, you might even decide to use a 10,000RPM drive. Faster drives cost more, are louder, have greater cooling needs, and use more power, but they may be a good option.
New disk technologies enable hard drives to be bigger and faster. These technologies include filling the drive with helium instead of air to reduce disk platter friction and using heat or microwaves to improve disk density, such as with heat-assisted magnetic recording (HAMR) drives and microwave-assisted magnetic recording (MAMR) drives.
Today, SSDs are becoming increasingly popular for computer storage. This type of computer storage is popular because it is faster, cooler, and takes up less space than traditional hard drives. They’re also less susceptible to magnetic fields and physical jolts, which makes them great for laptops.
For more about the difference between HDDs and SSDs, check out our post, “Hard Disk Drive (HDD) vs. Solid-state Drive (SSD): What’s the Diff?”
As a user’s disk storage needs increase, typically they will look to larger drives to store more data. The first step might be to replace an existing drive with a larger, faster drive. Or you might decide to install a second drive. One approach is to use different drives for different purposes. For example, use an SSD for the operating system, and then store your business videos on a larger SSD.
If more storage space is needed, you can also use an external drive, most often using USB or Thunderbolt to connect to the computer. This can be a single drive or multiple drives and might use a data storage virtualization technology such as RAID to protect the data.
If you have really large amounts of data, or simply wish to make it easy to share data with others in your location or elsewhere, you might consider network-attached storage (NAS). A NAS device can hold multiple drives, typically uses a data virtualization technology like RAID, and is accessible to anyone on your local network and—if you wish—on the internet, as well. NAS devices can offer a great deal of storage and other services that typically have been offered only by dedicated network servers in the past.
As a cloud storage company, we’d be remiss not to mention that you should back up your computer. No matter how you configure your computer’s storage, remember that technology can fail (we know a thing or two about that). You always want a backup so you can restore everything easily. The best backup strategy shouldn’t be dependent on any single device, either. Your backup strategy should always include three copies of your data on two different mediums with one off-site.
Internal storage is a method of data storage that writes data to a disk, holding onto that data until it’s erased. Think of it as your computer’s brain. RAM is a method of communicating data between your device’s CPU and its internal storage. Think of it as your brain’s short-term memory and ability to multi-task. The data the RAM receives is volatile, so it will only last until it’s no longer needed, usually when you turn off the power or reset the computer.
If you’re looking for better PC performance, you can upgrade either RAM or storage for a boost in performance. More RAM will make it easier for your computer to perform multiple tasks at once, while upgrading your storage will improve battery life, make it faster to open applications and files, and give you more space for photos and applications. This is especially true if you’re switching your storage from a hard disk drive (HDD) to a solid state drive (SSD).
More RAM does not provide you with more free space. If your computer is giving you notifications that you’re getting close to running out of storage or you’ve already started having to delete files to make room for new ones, you should upgrade the internal storage, not the RAM.
Memory and storage are also not the same thing, even though the words are often used interchangeably. Memory is another term for RAM.
The post What’s the Diff: RAM vs. Storage appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.
Post Syndicated from corbet original https://lwn.net/Articles/960088/
Filesystem development is not an easy task; the performance demands are
typically high, and the consequences for mistakes usually involve lost data
and irate users. The implementation of a virtual (or “pseudo”) filesystem
— a filesystem implemented within the kernel and lacking a normal backing
store — can also be challenging, but for different reasons. A series of
conversations around the eventfs virtual filesystem has turned a spotlight
on the difficulty of creating a virtual filesystem for Linux.
Post Syndicated from The Hook Up original https://www.youtube.com/watch?v=y3qL9o7CvEA
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=UButm1BuVMc
Post Syndicated from corbet original https://lwn.net/Articles/960446/
A new version of the Damn Small
Linux distribution has come out with an updated definition of “damn
small”:
The new goal of DSL is to pack as much usable desktop distribution
into an image small enough to fit on a single CD, or a hard limit
of 700MB. This project is meant to service older computers and have
them continue to be useful far into the future. Such a notion sits
well with my values. I think of this project as my way of keeping
otherwise usable hardware out of landfills.
Post Syndicated from jake original https://lwn.net/Articles/960439/
The 6.7.3, 6.6.15, and 6.1.76 stable kernels have been released.
These contain a large number of important fixes throughout the tree, as is
the norm.
Post Syndicated from jake original https://lwn.net/Articles/960436/
Security updates have been issued by Debian (debian-security-support, firefox-esr, openjdk-11, and python-asyncssh), Fedora (glibc, python-templated-dictionary, thunderbird, and xorg-x11-server-Xwayland), Gentoo (Chromium, Google Chrome, Microsoft Edge and WebKitGTK+), Red Hat (firefox, gnutls, libssh, thunderbird, and tigervnc), SUSE (mbedtls, rear116, rear1172a, runc, squid, and tinyssh), and Ubuntu (glibc and runc).
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/02/facebooks-extensive-surveillance-network.html
Consumer Reports is reporting that Facebook has built a massive surveillance network:
Using a panel of 709 volunteers who shared archives of their Facebook data, Consumer Reports found that a total of 186,892 companies sent data about them to the social network. On average, each participant in the study had their data sent to Facebook by 2,230 companies. That number varied significantly, with some panelists’ data listing over 7,000 companies providing their data. The Markup helped Consumer Reports recruit participants for the study. Participants downloaded an archive of the previous three years of their data from their Facebook settings, then provided it to Consumer Reports.
This isn’t data about your use of Facebook. This data about your interactions with other companies, all of which is correlated and analyzed by Facebook. It constantly amazes me that we willingly allow these monopoly companies that kind of surveillance power.
Here’s the Consumer Reports study. It includes policy recommendations:
Many consumers will rightly be concerned about the extent to which their activity is tracked by Facebook and other companies, and may want to take action to counteract consistent surveillance. Based on our analysis of the sample data, consumers need interventions that will:
- Reduce the overall amount of tracking.
- Improve the ability for consumers to take advantage of their right to opt out under state privacy laws.
- Empower social media platform users and researchers to review who and what exactly is being advertised on Facebook.
- Improve the transparency of Facebook’s existing tools.
And then the report gives specifics.
Post Syndicated from Joanne Vincent original https://www.raspberrypi.org/blog/code-editor-integration/
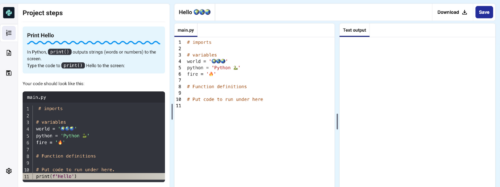
We’re currently trialling the full integration of our Code Editor in some of the projects on our Projects site, with the aim of providing a seamless experience for young learners. Our Projects site provides hundreds of free coding projects with step-by-step instructions for young people to use at school, in Code Clubs and CoderDojo clubs, and at home. When learners make text-based programming projects in our Python and web design project paths, they use our Code Editor to write and run code in a web browser.
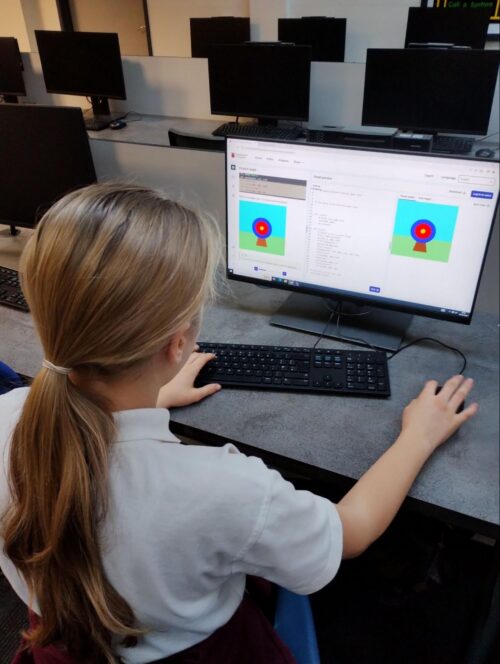
Our new integrated learning experience allows young people to follow the project instructions and work in the Code Editor in a single window. By providing a simpler workspace, where learners do not need to switch between windows to read instructions and input code, we aim to reduce cognitive load and make it easier for young people to learn.
In the integrated project workspace, learners can access the project instructions, coding area, and output (where they can see what they have made) all in the same view. We have reorganised the project guides into short, easy-to-follow steps made up of simple instructions, including code snippets and modelled examples, for learners to work through to create their projects. The project guides feature fresh designs for different types of learning content, such as instruction steps, concept steps, code snippets, tips, and debugging help.
We have also optimised this learning experience for young people using mobiles and tablets. On mobile devices, a new ‘Steps’ tab appears alongside the ‘Code’ and ‘Output’ tabs, enabling learners to easily navigate to the project guide and follow the steps to make their projects.
We are testing our new integrated learning experience as a beta version in three projects:
In each of these projects, young people can choose to complete the original version of the project, with the project instructions and Code Editor in separate windows, or click the button on the project page to try out the new integrated learning experience.
We’d love to hear how your young learners get on with this new integrated experience. Try it out in the three projects above and share your feedback with us here.
Code Editor developments have been made possible with generous support from the Cisco Foundation.
The post An integrated learning experience for young people appeared first on Raspberry Pi Foundation.
Post Syndicated from Aleksandr Iantsen original https://blog.zabbix.com/python-zabbix-utils/27056/
Zabbix is a flexible and universal monitoring solution that integrates with a wide variety of different systems right out of the box. Despite actively expanding the list of natively supported systems for integration (via templates or webhook integrations), there may still be a need to integrate with custom systems and services that are not yet supported. In such cases, a library taking care of implementing interaction protocols with the Zabbix API, Zabbix server/proxy, or Agent/Agent2 becomes extremely useful. Given that Python is widely adopted among DevOps and SRE engineers as well as server administrators, we decided to release a library for this programming language first.
We are pleased to introduce zabbix_utils – a Python library for seamless interaction with Zabbix API, Zabbix server/proxy, and Zabbix Agent/Agent2. Of course, there are popular community solutions for working with these Zabbix components in Python. Keeping this fact in mind, we have tried to consolidate popular issues and cases along with our experience to develop as convenient a tool as possible. Furthermore, we made sure that transitioning to the tool is as straightforward and clear as possible. Thanks to official support, you can be confident that the current version of the library is compatible with the latest Zabbix release.
In this article, we will introduce you to the main capabilities of the library and provide examples of how to use it with Zabbix components.
The zabbix_utils library can be used in the following scenarios, but is not limited to them:
You can use zabbix_utils for automating Zabbix tasks, such as scripting the automatic monitoring setup of your IT infrastructure objects. This can involve using ZabbixAPI for the direct management of Zabbix objects, Sender for sending values to hosts, and Getter for gathering data from Agents. We will discuss Sender and Getter in more detail later in this article.
For example, let’s imagine you have an infrastructure consisting of different branches. Each server or workstation is deployed from an image with an automatically configured Zabbix Agent and each branch is monitored by a Zabbix proxy since it has an isolated network. Your custom service or script can fetch a list of this equipment from your CMDB system, along with any additional information. It can then use this data to create hosts in Zabbix and link the necessary templates using ZabbixAPI based on the received information. If the information from CMDB is insufficient, you can request data directly from the configured Zabbix Agent using Getter and then use this information for further configuration and decision-making during setup. Another part of your script can access AD to get a list of branch users to update the list of users in Zabbix through the API and assign them the appropriate permissions and roles based on information from AD or CMDB (e.g., editing rights for server owners).
Another use case of the library may be when you regularly export templates from Zabbix for subsequent import into a version control system. You can also establish a mechanism for loading changes and rolling back to previous versions of templates. Here a variety of other use cases can also be implemented – it’s all up to your requirements and the creative usage of the library.
Of course, if you are a developer and there is a requirement to implement Zabbix monitoring support for your custom system or tool, you can implement sending data describing any events generated by your custom system/tool to Zabbix using Sender.
To begin with, you need to install the zabbix_utils library. You can do this in two main ways:
~$ pip install zabbix_utils
~$ git clone https://github.com/zabbix/python-zabbix-utils
~$ cd python-zabbix-utils/
~$ python setup.py install
No additional configuration is required. But you can specify values for the following environment variables: ZABBIX_URL, ZABBIX_TOKEN, ZABBIX_USER, ZABBIX_PASSWORD if you need. These use cases are described in more detail below.
To work with Zabbix API, it is necessary to import the ZabbixAPI class from the zabbix_utils library:
from zabbix_utils import ZabbixAPI
If you are using one of the existing popular community libraries, in most cases, it will be sufficient to simply replace the ZabbixAPI import statement with an import from our library.
At that point you need to create an instance of the ZabbixAPI class. T4here are several usage scenarios:
~$ export ZABBIX_URL="https://zabbix.example.local"
~$ export ZABBIX_USER="Admin"
~$ export ZABBIX_PASSWORD="zabbix"
from zabbix_utils import ZabbixAPI


api = ZabbixAPI()
~$ export ZABBIX_USER="Admin"
~$ export ZABBIX_PASSWORD="zabbix"
from zabbix_utils import ZabbixAPI

api = ZabbixAPI(url="127.0.0.1")
from zabbix_utils import ZabbixAPI

api = ZabbixAPI(url="127.0.0.1")
api.login(user="Admin", password="zabbix")
from zabbix_utils import ZabbixAPI

api = ZabbixAPI(
    url="127.0.0.1",
    user="Admin",
    password="zabbix"
)
The ZabbixAPI class supports working with various Zabbix versions, automatically checking the API version during initialization. You can also work with the Zabbix API version as an object as follows:
from zabbix_utils import ZabbixAPI

api = ZabbixAPI()

# ZabbixAPI version field
ver = api.version
print(type(ver).__name__, ver) # APIVersion 6.0.24

# Method to get ZabbixAPI version
ver = api.api_version()
print(type(ver).__name__, ver) # APIVersion 6.0.24

# Additional methods
print(ver.major)    # 6.0
print(ver.minor)    # 24
print(ver.is_lts()) # True
As a result, you will get an APIVersion object that has major and minor fields returning the respective minor and major parts of the current version, as well as the is_lts() method, returning true if the current version is LTS (Long Term Support), and false otherwise. The APIVersion object can also be compared to a version represented as a string or a float number:
# Version comparison
print(ver < 6.4)      # True
print(ver != 6.0)     # False
print(ver != "6.0.5") # True
If the account and password (or starting from Zabbix 5.4 – token instead of login/password) are not set as environment variable values or during the initialization of ZabbixAPI, then it is necessary to call the login() method for authentication:
from zabbix_utils import ZabbixAPI

api = ZabbixAPI(url="127.0.0.1")
api.login(token="xxxxxxxx")
After authentication, you can make any API requests described for all supported versions in the Zabbix documentation.
The format for calling API methods looks like this:
api_instance.zabbix_object.method(parameters)
For example:
api.host.get()
After completing all the necessary API requests, it’s necessary to execute logout() if authentication was done using login and password:
api.logout()
More examples of usage can be found here.
There is often a need to send values to Zabbix Trapper. For this purpose, the zabbix_sender utility is provided. However, if your service or script sending this data is written in Python, calling an external utility may not be very convenient. Therefore, we have developed the Sender, which will help you send values to Zabbix server or proxy one by one or in groups. To work with Sender, you need to import it as follows:
from zabbix_utils import Sender
After that, you can send a single value:
from zabbix_utils import Sender

sender = Sender(server='127.0.0.1', port=10051)
resp = sender.send_value('example_host', 'example.key', 50, 1702511920)
Alternatively, you can put them into a group for simultaneous sending, for which you need to additionally import ItemValue:
from zabbix_utils import ItemValue, Sender


items = [
    ItemValue('host1', 'item.key1', 10),
    ItemValue('host1', 'item.key2', 'Test value'),
    ItemValue('host2', 'item.key1', -1, 1702511920),
    ItemValue('host3', 'item.key1', '{"msg":"Test value"}'),
    ItemValue('host2', 'item.key1', 0, 1702511920, 100)
]

sender = Sender('127.0.0.1', 10051)
response = sender.send(items)
For cases when there is a necessity to send more values than Zabbix Trapper can accept at one time, there is an option for fragmented sending, i.e. sequential sending in separate fragments (chunks). By default, the chunk size is set to 250 values. In other words, when sending values in bulk, the 400 values passed to the send() method for sending will be sent in two stages. 250 values will be sent first, and the remaining 150 values will be sent after receiving a response. The chunk size can be changed, to do this, you simply need to specify your value for the chunk_size parameter when initializing Sender:
from zabbix_utils import ItemValue, Sender


items = [
    ItemValue('host1', 'item.key1', 10),
    ItemValue('host1', 'item.key2', 'Test value'),
    ItemValue('host2', 'item.key1', -1, 1702511920),
    ItemValue('host3', 'item.key1', '{"msg":"Test value"}'),
    ItemValue('host2', 'item.key1', 0, 1702511920, 100)
]

sender = Sender('127.0.0.1', 10051, chunk_size=2)
response = sender.send(items)
In the example above, the chunk size is set to 2. So, 5 values passed will be sent in three requests of two, two, and one value, respectively.
If your server has multiple network interfaces, and values need to be sent from a specific one, the Sender provides the option to specify a source_ip for the sent values:
from zabbix_utils import Sender

sender = Sender(
    server='zabbix.example.local',
    port=10051,
    source_ip='10.10.7.1'
)
resp = sender.send_value('example_host', 'example.key', 50, 1702511920)
It also supports reading connection parameters from the Zabbix Agent/Agent2 configuration file. To do this, set the use_config flag, after which it is not necessary to pass connection parameters when creating an instance of Sender:
from zabbix_utils import Sender

sender = Sender(
    use_config=True,
    config_path='/etc/zabbix/zabbix_agent2.conf'
)
response = sender.send_value('example_host', 'example.key', 50, 1702511920)
Since the Zabbix Agent/Agent2 configuration file can specify one or even several Zabbix clusters consisting of multiple Zabbix server instances, Sender will send data to the first available server of each cluster specified in the ServerActive parameter in the configuration file. In case the ServerActive parameter is not specified in the Zabbix Agent/Agent2 configuration file, the server address from the Server parameter with the standard Zabbix Trapper port – 10051 will be taken.
By default, Sender returns the aggregated result of sending across all clusters. But it is possible to get more detailed information about the results of sending for each chunk and each cluster:
print(response)
# {"processed": 2, "failed": 0, "total": 2, "time": "0.000108", "chunk": 2}

if response.failed == 0:
    print(f"Value sent successfully in {response.time}")
else:
    print(response.details)
    # {
    #     127.0.0.1:10051: [
    #         {
    #             "processed": 1,
    #             "failed": 0,
    #             "total": 1,
    #             "time": "0.000051",
    #             "chunk": 1
    #         }
    #     ],
    #     zabbix.example.local:10051: [
    #         {
    #             "processed": 1,
    #             "failed": 0,
    #             "total": 1,
    #             "time": "0.000057",
    #             "chunk": 1
    #         }
    #     ]
    # }
    for node, chunks in response.details.items():
        for resp in chunks:
            print(f"processed {resp.processed} of {resp.total} at {node.address}:{node.port}")
            # processed 1 of 1 at 127.0.0.1:10051
            # processed 1 of 1 at zabbix.example.local:10051
More usage examples can be found here.
Sometimes it can also be useful to directly retrieve values from the Zabbix Agent. To assist with this task, zabbix_utils provides the Getter. It performs the same function as the zabbix_get utility, allowing you to work natively within Python code. Getter is straightforward to use; just import it, create an instance by passing the Zabbix Agent’s address and port, and then call the get() method, providing the data item key for the value you want to retrieve:
from zabbix_utils import Getter

agent = Getter('10.8.54.32', 10050)
resp = agent.get('system.uname')
In cases where your server has multiple network interfaces, and requests need to be sent from a specific one, you can specify the source_ip for the Agent connection:
from zabbix_utils import Getter

agent = Getter(
    host='zabbix.example.local',
    port=10050,
    source_ip='10.10.7.1'
)
resp = agent.get('system.uname')
The response from the Zabbix Agent will be processed by the library and returned as an object of the AgentResponse class:
print(resp)
# {
#     "error": null,
#     "raw": "Linux zabbix_server 5.15.0-3.60.5.1.el9uek.x86_64",
#     "value": "Linux zabbix_server 5.15.0-3.60.5.1.el9uek.x86_64"
# }

print(resp.error)
# None

print(resp.value)
# Linux zabbix_server 5.15.0-3.60.5.1.el9uek.x86_64
More usage examples can be found here.
The zabbix_utils library for Python allows you to take full advantage of monitoring using Zabbix, without limiting yourself to the integrations available out of the box. It can be valuable for both DevOps and SRE engineers, as well as Python developers looking to implement monitoring support for their system using Zabbix.
In the next article, we will thoroughly explore integration with an external service using this library to demonstrate the capabilities of zabbix_utils more comprehensively.
Q: Which Agent versions are supported for Getter?
A: Supported versions of Zabbix Agents are the same as Zabbix API versions, as specified in the readme file. Our goal is to create a library with full support for all Zabbix components of the same version.
Q: Does Getter support Agent encryption?
A: Encryption support is not yet built into Sender and Getter, but you can create your wrapper using third-party libraries for both.
from zabbix_utils import Sender

def psk_wrapper(sock, tls):
    # ...
    # Implementation of TLS PSK wrapper for the socket
    # ...

sender = Sender(
    server='zabbix.example.local',
    port=10051,
    socket_wrapper=psk_wrapper
)
More examples can be found here.
Q: Is it possible to set a timeout value for Getter?
A: The response timeout value can be set for the Getter, as well as for ZabbixAPI and Sender. In all cases, the timeout is set for waiting for any responses to requests.
# Example of setting a timeout for Sender
sender = Sender(server='127.0.0.1', port=10051, timeout=30)

# Example of setting a timeout for Getter
agent = Getter(host='127.0.0.1', port=10050, timeout=30)
Q: Is parallel (asynchronous) mode supported?
A: Currently, the library does not include asynchronous classes and methods, but we plan to develop asynchronous versions of ZabbixAPI and Sender.
Q: Is it possible to specify multiple servers when sending through Sender without specifying a configuration file (for working with an HA cluster)?
A: Yes, it’s possible by the following way:
from zabbix_utils import Sender


zabbix_clusters = [
    [
        'zabbix.cluster1.node1',
        'zabbix.cluster1.node2:10051'
    ],
    [
        'zabbix.cluster2.node1:10051',
        'zabbix.cluster2.node2:20051',
        'zabbix.cluster2.node3'
    ]
]

sender = Sender(clusters=zabbix_clusters)
response = sender.send_value('example_host', 'example.key', 10, 1702511922)

print(response)
# {"processed": 2, "failed": 0, "total": 2, "time": "0.000103", "chunk": 2}

print(response.details)
# {
#     "zabbix.cluster1.node1:10051": [
#         {
#             "processed": 1,
#             "failed": 0,
#             "total": 1,
#             "time": "0.000050",
#             "chunk": 1
#         }
#     ],
#     "zabbix.cluster2.node2:20051": [
#         {
#             "processed": 1,
#             "failed": 0,
#             "total": 1,
#             "time": "0.000053",
#             "chunk": 1
#         }
#     ]
# }
The post Introducing zabbix_utils – the official Python library for Zabbix API appeared first on Zabbix Blog.
Post Syndicated from Тоест original https://www.toest.bg/toest-na-6/

Скъпи приятели на „Тоест“, станахме на 6 години!
„Станахме“, защото всички ние заедно – екип и читатели, правим медията „Тоест“. Този рожден ден е празник колкото за хората от екипа, толкова и за всички вас, които вече 6 години ни подкрепяте и абсолютно безкомпромисно ни доказвате, че една качествена медия може да се издържа благодарение на своята взискателна, активна и вярна публика. Благодарим ви от сърце, че сме заедно!
Черпим всички с шоколади на корем от „Гайо“, които може да поръчате тук. Пускаме духовата музика в сърцата и душите и вперваме поглед в хоризонта на седмата година, в която си пожелаваме отново да пристигнем заедно. За да се случи това, продължавайте да ни подкрепяте. Ето какви са начините: https://www.toest.bg/support/
Пращаме ви сърца и живи цветя и не смеем да си пожелаем нищо повече, защото най-важното за една медия вече го имаме – публика като вас! Честит „Тоест“!
Post Syndicated from Светла Енчева original https://www.toest.bg/prava-na-semeystvoto-ili-prava-na-deteto/

Чували сте да се говори за семейството, сякаш то е личност, която има права. Или по-скоро дете в риск, което има нужда от закрила. Да припомним например новогодишното изявление на президентите на Унгария, Сърбия и България, в което се казваше, че семействата „заслужават закрила, помощ и признание“. Разбира се, в името на децата. На правото на семействата да отглеждат децата си, както намерят за добре, се противопоставя безличната държавна машина, която отнема деца от родителите им. Но винаги ли родителите са най-доброто за едно дете?
Последният случай, разбунил духовете, е за момче на 13 или 14 години, което не желае да живее с родителите си. Причините за това са, че то няма достъп до образование (освен като частен ученик или в нелицензирани училища), нито до здравеопазване и иска да живее като другите деца. За случая се разчува от репортаж на БНТ и продължението му. При опита на родителите да изведат детето си от страната то е потърсило помощ от полицаите на летището, след което е пожелало да бъде настанено в център за социални услуги.
Министерството на труда и социалната политика излезе със становище по случая, на който дава гласност и Албена Тодорова – една от лелите на тийнейджъра. Тя разказва как той нееднократно е заявявал, че иска да има нормален дом в България, а не да живее в Бразилия, където няма постоянно жилище и където пребивава с родителите си, вярващи във всевъзможни конспиративни теории. При опит да бъде насила изведено от училището в България, в което е записано, момчето е ударено от приятел на майката и челюстта му е счупена. След това обаче майката продължавала да събира детето и този човек на едно място.
За „Тоест“ Тодорова уточни, че ученици от по-горен клас са се притекли на помощ на момчето, както и че то вече може да се храни самостоятелно, но няма как да бъде заведено на лекар, защото роднините, които се грижат за него, не са му попечители, нито настойници.
Майката на детето от своя страна обвинява роднините, че са го манипулирали. Тя отрича да го е удряла и твърди, че то няма нараняване, но не коментира информацията друг човек да е упражнил насилие върху него. Във Facebook майката публикува десетки снимки на момчето като доказателство колко щастливо и пълноценно е живяло то под грижите на родителите си. По този начин тя излага публично лични данни на дете против волята му.
Случаят с тийнейджъра, който не иска да живее с родителите си, даде повод за полярни реакции. Докато едни подкрепят желанието на неговите баби и лели да му осигурят нормална среда на живот, за други така се нарушава правото на родителите да отглеждат детето си според собствените си разбирания. За тях по дефиниция родителите имат право, а държавата е в ролята на лошата мащеха.
Подобни дискусии имаше и във връзка с друг случай – на майката, родила и отглеждаща детето си съвсем сама и в пълна изолация и наричаща го Буда. В продължение на три години тя дори е отказвала да го регистрира и то да получи ЕГН, за да не попадне в „дяволската система“. Детето е живяло без достъп до ток и течаща вода, да не говорим за здравеопазване. Но пък в компанията на много ножове. Първото бебе на майката е починало по време на домашно раждане.
И при този казус част от общественото мнение застана на страната на майката и на правото ѝ да отглежда своето дете в съответствие със собствените си ценности. Не само въпреки законите, а и въпреки рисковете за здравето, живота и развитието на момченцето. Решението детето да бъде настанено в приемно семейство, а майката – в център за психично здраве, стана обект на остри критики.
Няколко месеца по-късно детето е върнато на майка си и те живеят при свой познат. То вече има ЕГН и е регистрирано с името Атанас, а жената продължава да получава подкрепа от социалните служби, включително и за психичното си заболяване, което е установено.
Защитата на родителите в случаи като тези, за които стана дума, е в духа на кампанията срещу Стратегията за детето през 2019 г., довела до неприемането ѝ. Тя се разгърна по начин, подобен на кампанията срещу Истанбулската конвенция. А и двигателите ѝ бяха, общо взето, същите, като започнем от Александър Урумов – тогавашния пиар на Военното министерство, политик от ВМРО, евангелски проповедник и агент на ДС. Лайтмотивът беше, че ако Стратегията се приеме, държавата ще отнема деца от родителите им „заради едно шамарче“.
Кампанията сериозно затрудни дейността на организациите, работещи в сферата на закрилата на децата, като някои от тях станаха обект и на заплахи. Тя продължи дълго време след като Стратегията не беше приета. В края на 2020 г. например ВМРО внесоха проект за промяна в Закона за закрила на детето с аргумента, че „детето не е отделен субект и това трябва ясно да залегне във всички нормативни актове, които касаят материята“.
Докато България продължава да няма стратегически документ за децата, през 2022 г. беше приета европейска Стратегия за правата на детето (2022–2027). Сред най-важните ѝ цели са свобода от насилие за всички деца и даване на глас на всяко дете. В нея детето се разглежда като личност с права, а не като обект, подвластен на родителите си или на държавата.
Впрочем наблюдава се една интересна особеност в нагласите към правата на родителите, децата и ролята на държавата в регулирането им. Когато се предпоставя абсолютното право на родителите да определят кое е най-доброто за децата им, се имат предвид основно семейства на етнически българи. Що се отнася до ромските родители, общественото мнение застава на страната на държавата и законите.
Така например много критики и подигравки отнесоха родителите от ромските махали в няколко града, които в края на 2019 г. едновременно изпаднаха в паника, че социалните ще им вземат децата, и нахлуха в училищата да си ги приберат. Тогава тези родители бяха квалифицирани в социалните групи с епитети като „първобитни“. Такива епитети нямаше за родителите – етнически българи, страхуващи се, че зли норвежци могат да им откраднат децата.
По-сериозният проблем е, че за истерията в ромските махали не беше потърсена отговорност от онези, които размахваха Стратегията за детето като плашило, като започнем от Александър Урумов. В кампанията срещу Стратегията (както и срещу Истанбулската конвенция) бяха много гласовити някои евангелски църкви. Ромски родители, уплашени, че държавата ще им вземе децата, твърдяха, че са чули това от пастора на църквата в махалата.
Метафората за семейството като основна клетка на обществото е неоснователна, защото обществото не се състои от семейства. Затова пък е популярна. Организмите са изградени от клетки, но има и клетки, които „решават“ да се развиват „на своя глава“. Те започват да се размножават безконтролно, като по този начин вредят на организма и могат дори да го убият.
Обществото има механизми, благодарение на които се удържа като едно цяло. Сред най-важните от тях е образованието. Една от целите на публичното образование е да социализира децата, тоест да ги възпита в основните ценности и норми на дадено общество. Училището съвсем не е „безгрешно“, то има достатъчно „трески за дялане“. Но то е такова, каквото е и самото общество.
Ситуацията с публичното здравеопазване е подобна, доколкото не на последно място то би следвало да включва превенция на социално значими заболявания. Последствията от решенията на много семейства да не се доверяват на здравната система са очевидни. Отказът от ваксиниране на децата например води до връщане на заболявания като морбили и полиомиелит, които почти са изкоренени благодарение на масовите имунизации.
Ето защо, ако възприемаме семейството като клетка, добре е да имаме предвид, че тя може да бъде и туморна. Зачитането на правата на децата е важно преди всичко за самите деца, но далеч не само за тях. Няма как да се изгради читаво общество от хора, чиито собствени права не са били уважавани и които са научени, че всичко извън семейството е зло.
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/gigabyte-r183-z95-review-dual-amd-epyc-server-with-a-edsff-twist-kioxia/
The Gigabyte R183-Z95 is a 1U server with 17x NVMe SSD slots standard, along with dual AMD EPYC 9004 processors for a very cool system
The post Gigabyte R183-Z95 Review Dual AMD EPYC Server with a EDSFF Twist appeared first on ServeTheHome.
Post Syndicated from corbet original https://lwn.net/Articles/959457/
The LWN.net Weekly Edition for February 1, 2024 is available.
Post Syndicated from Grab Tech original https://engineering.grab.com/dynamic-marketplace
In the fast-paced world of on-demand delivery, maintaining safe marketplaces is a complex undertaking. Grab, a leading superapp in Southeast Asia, operates GrabFood and GrabMart, two popular marketplaces that connect consumers with a wide range of food and daily necessities. With more than 100k listings for different items updated daily by our merchants across eight different countries, Grab is rising to the challenge of ensuring that its marketplaces remain compliant with its own policies, government regulations as well as platform policies.
This article provides an overview of how Grab employs a combination of automated and manual content moderation to manage its dynamic marketplace content efficiently, while also collaborating with Google to ensure marketplace safety. Stay tuned for future articles that will delve deeper into the technology and solutions used for content moderation.
Marketplaces like GrabFood and GrabMart are at the forefront of connecting merchants and consumers. These marketplaces provide an avenue for merchants to showcase their offerings, enabling consumers to conveniently access a plethora of on-demand options. However, in an environment characterized by rapid changes as well as evolving regulatory frameworks, maintaining the integrity of these marketplaces becomes a formidable task.
The cornerstone of Grab’s success lies in its ability to adapt to the unique regulations and requirements of each country it operates in. This necessitates a nuanced and multifaceted approach to content moderation. To achieve both scale and flexibility, Grab employs a proactive strategy that combines and leverages automated and manual moderation processes.
Automated moderation plays a pivotal role in efficiently managing the high volume of listings that undergo daily updates. Grab utilises advanced algorithms and machine learning technologies, built in-house, to scan listings everyday for potential violations of its own policies, government regulations and platform policies. This automation not only speeds up the process to put eligible listings on the Grab platform, but also ensures consistent adherence to predefined guidelines. However, automated moderation is not without its limitations, as contextual understanding and subjective judgment often require human intervention.
Recognising the nuanced nature of content moderation, Grab employs a team of human moderators who possess the cultural awareness and contextual understanding necessary to assess complex cases. These moderators review listings flagged by algorithms and machine learning technologies that require human judgment, ensuring that content aligns with Grab’s policies, local regulations as well as platform policies. Manual moderation adds a layer of human insight that automated systems may lack, contributing to a more accurate and contextually sensitive approach.
In its commitment to ensuring marketplace safety, Grab has also established a strong collaboration with Google. Grab works hand in hand with Google to collectively ensure adherence to Play Store policies and guidelines.
Grab
Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 428 cities in eight countries.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
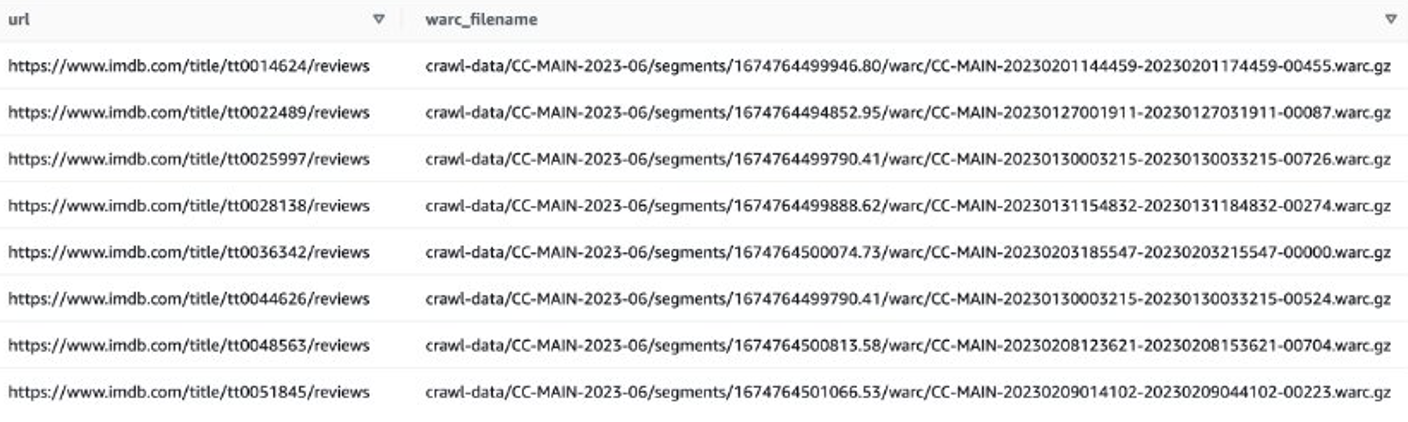
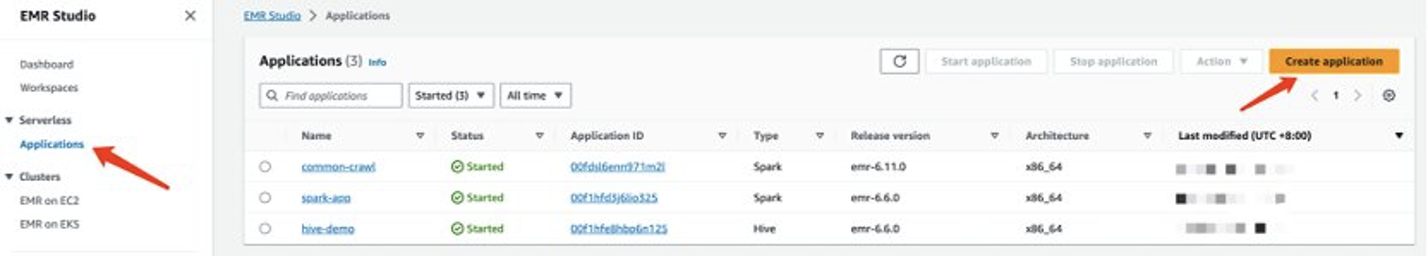
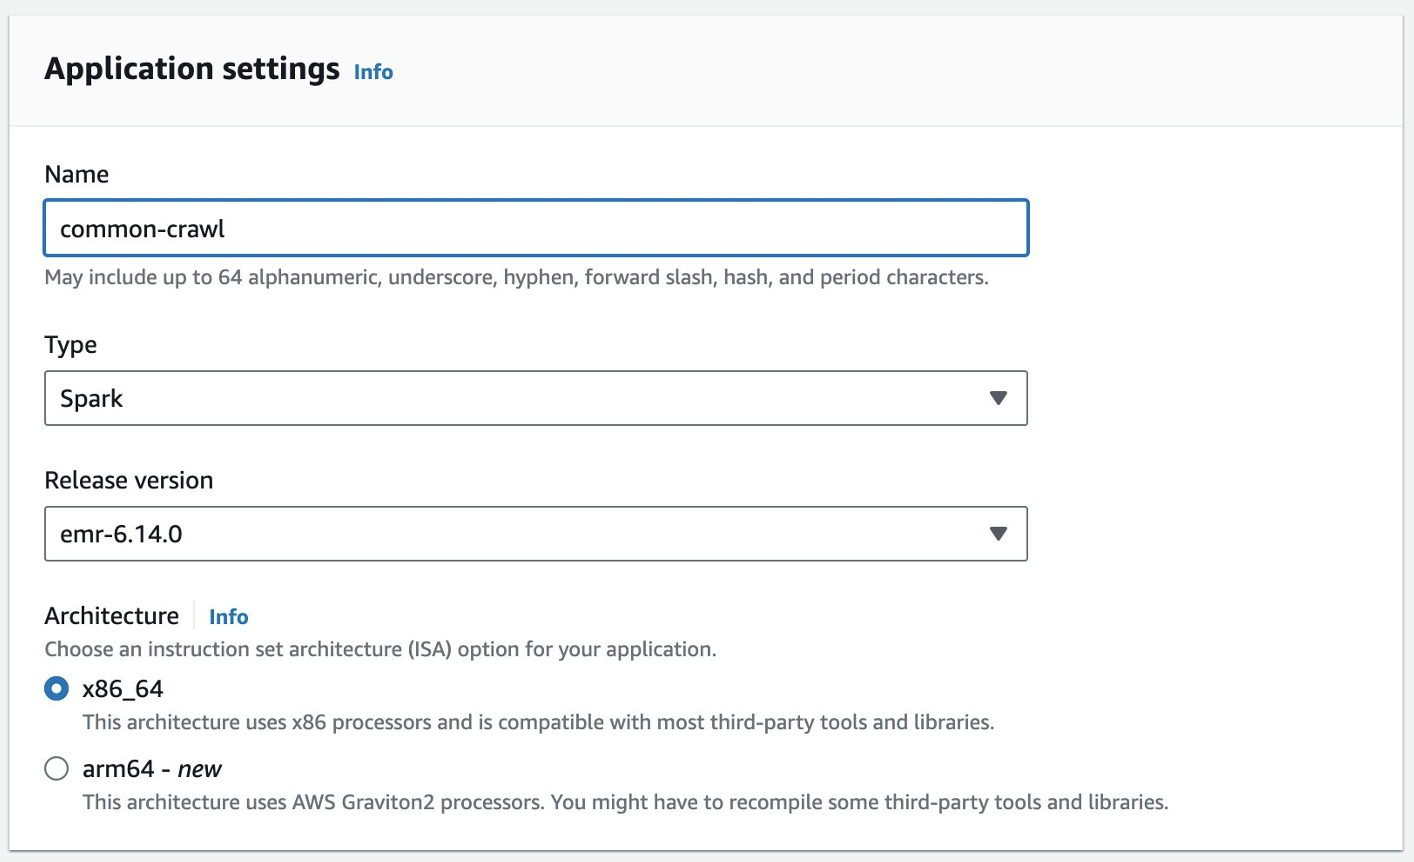
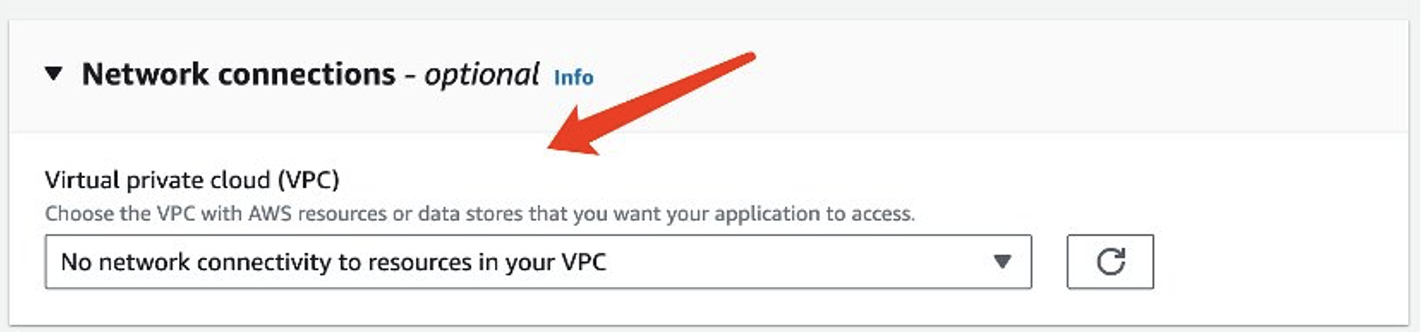
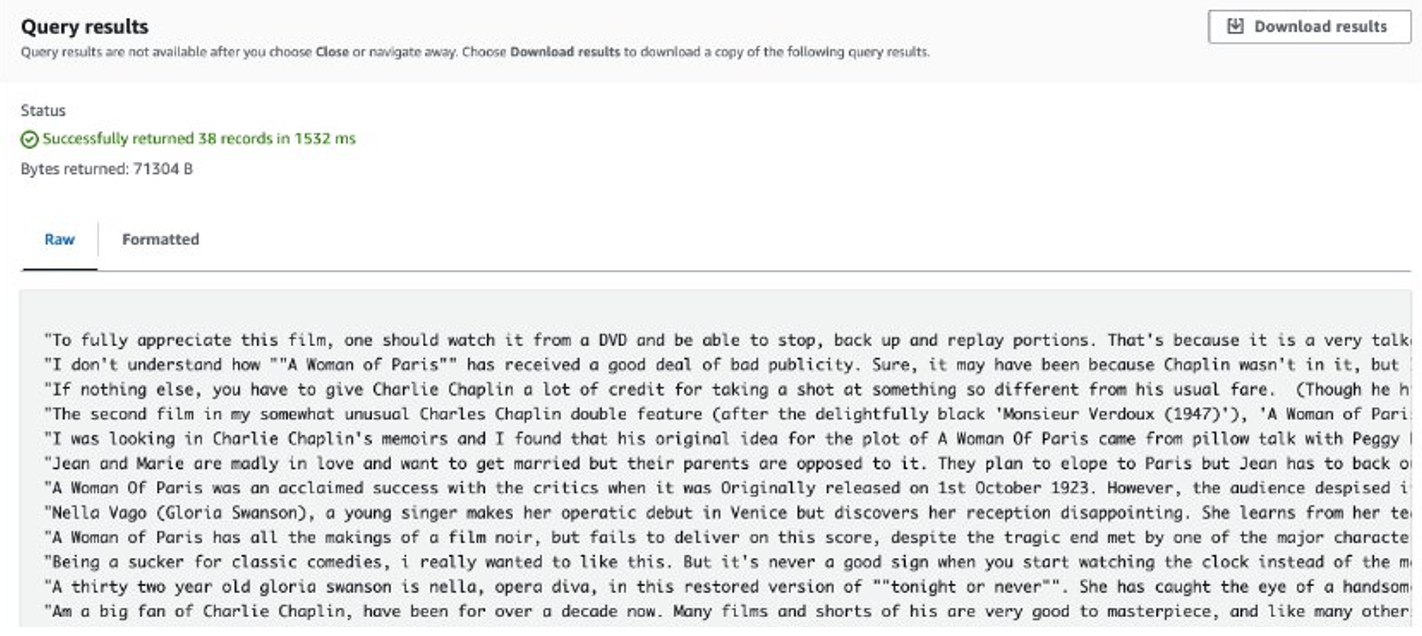
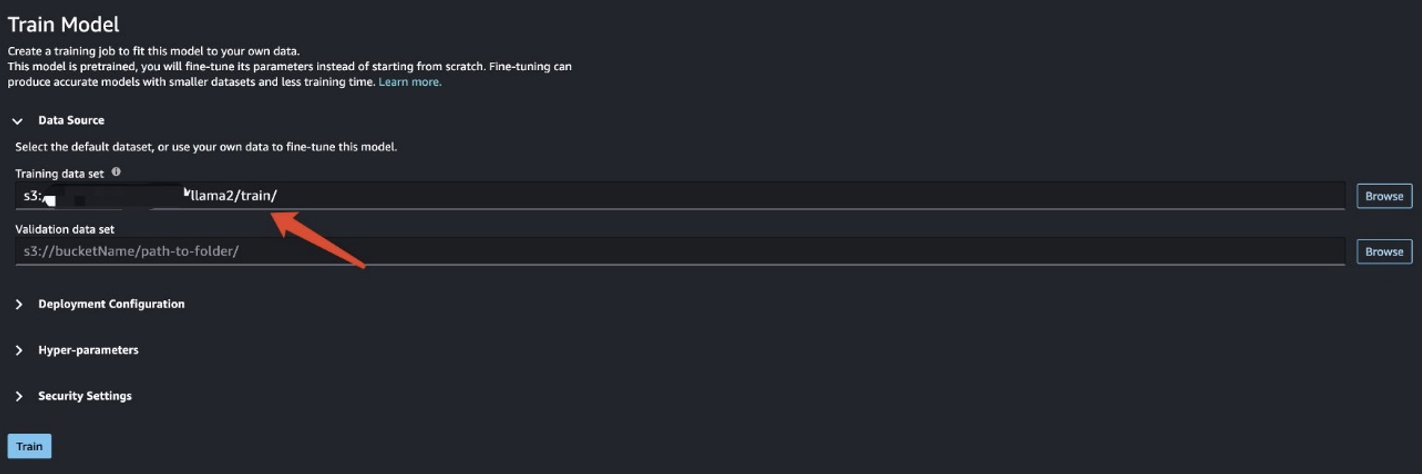
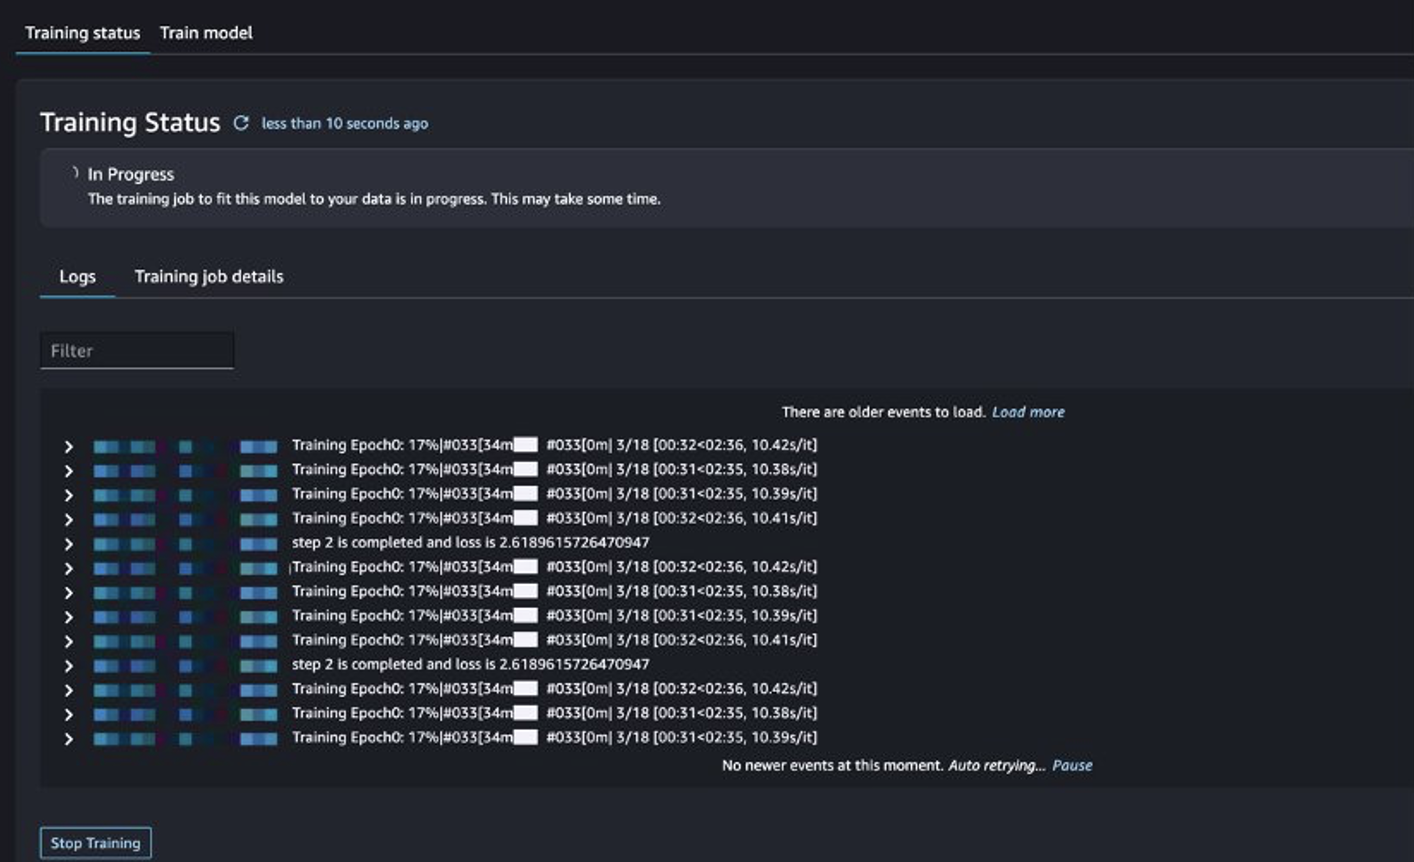
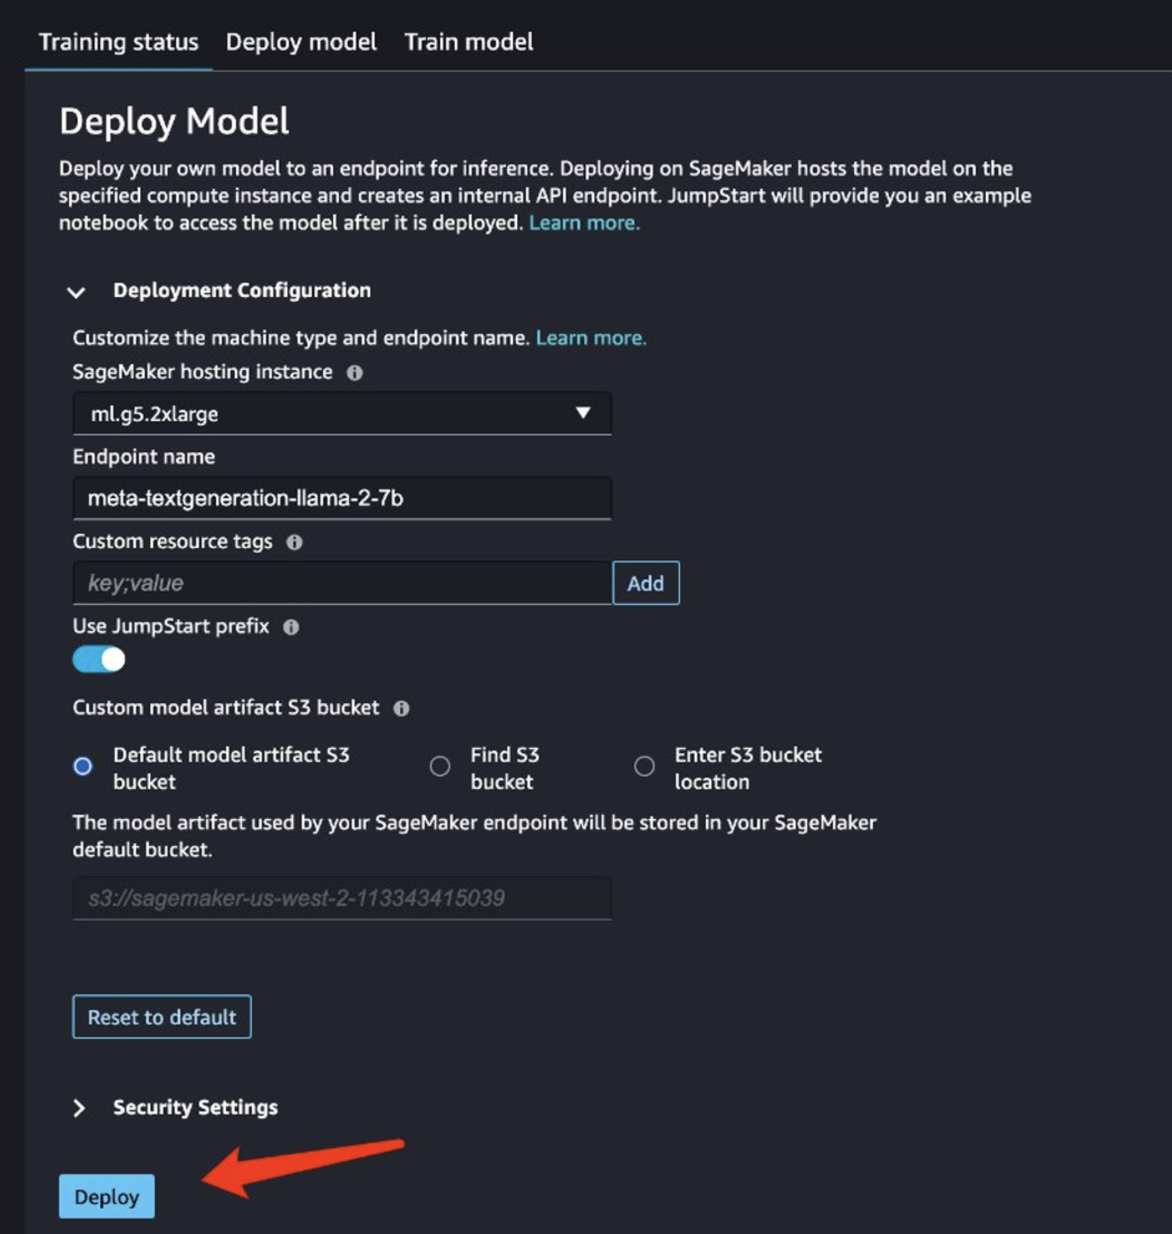
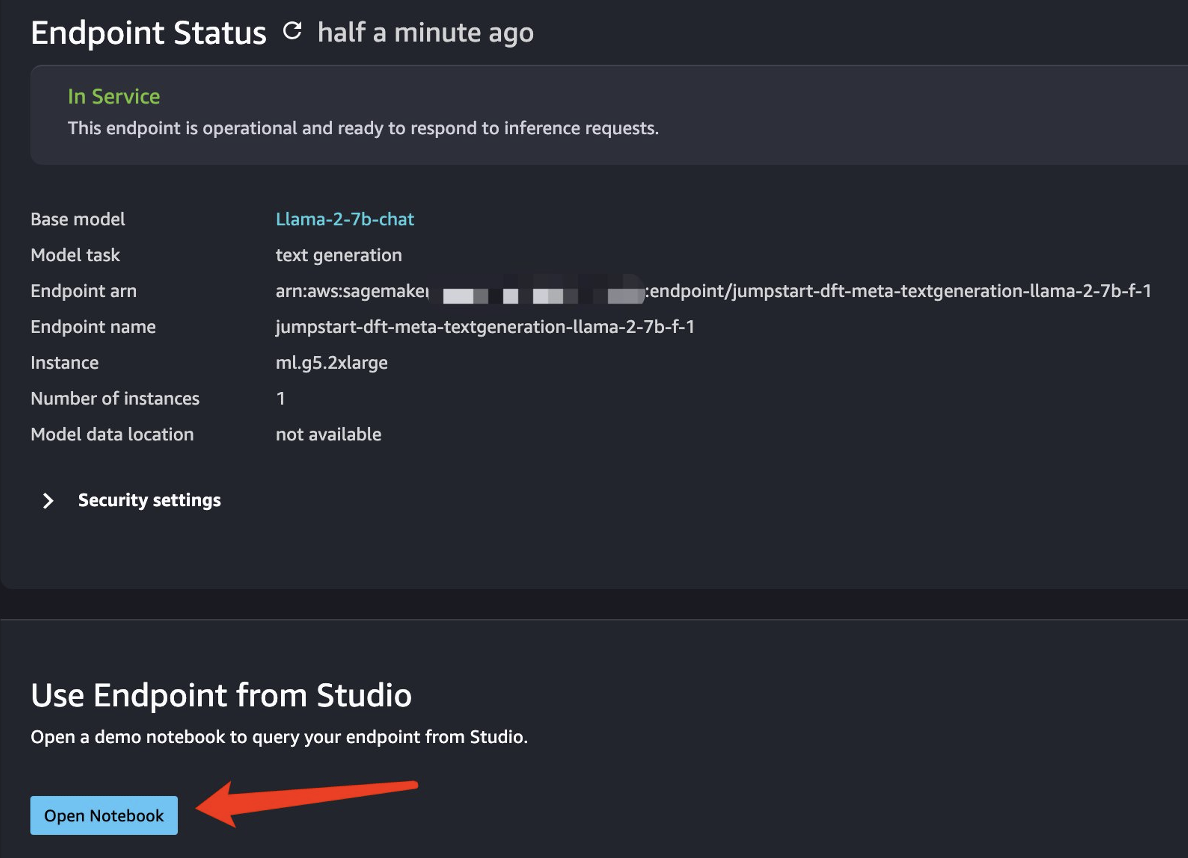
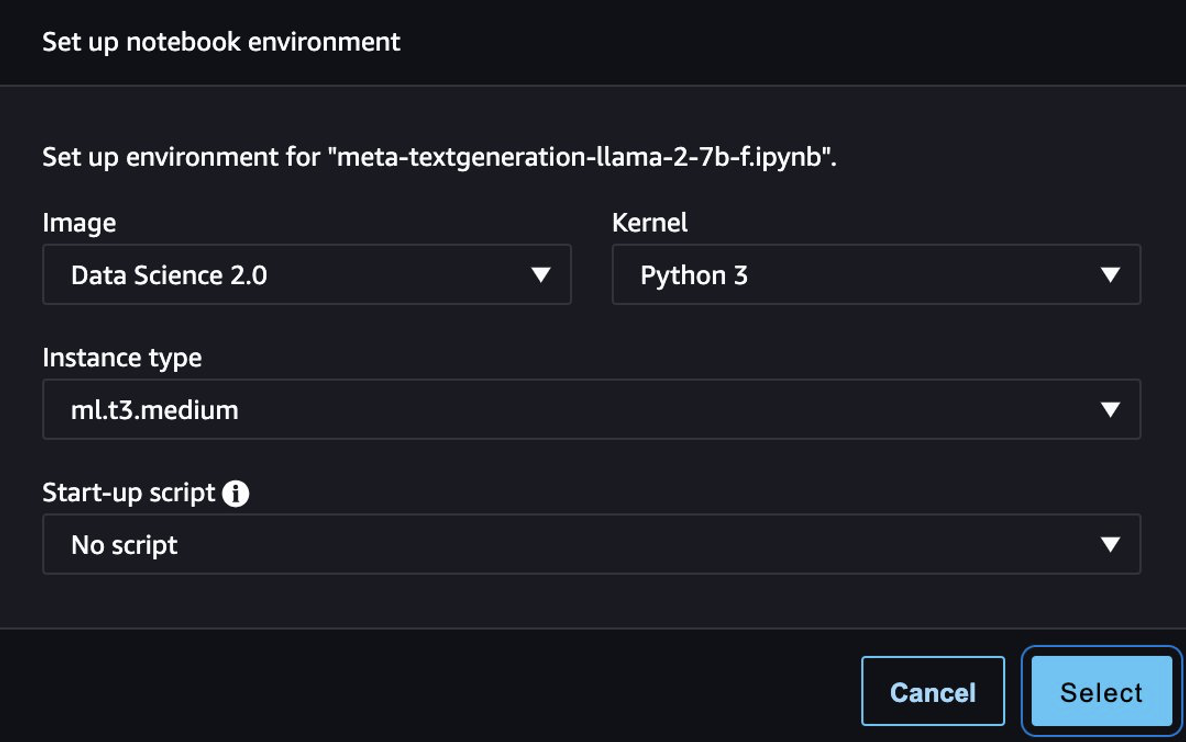
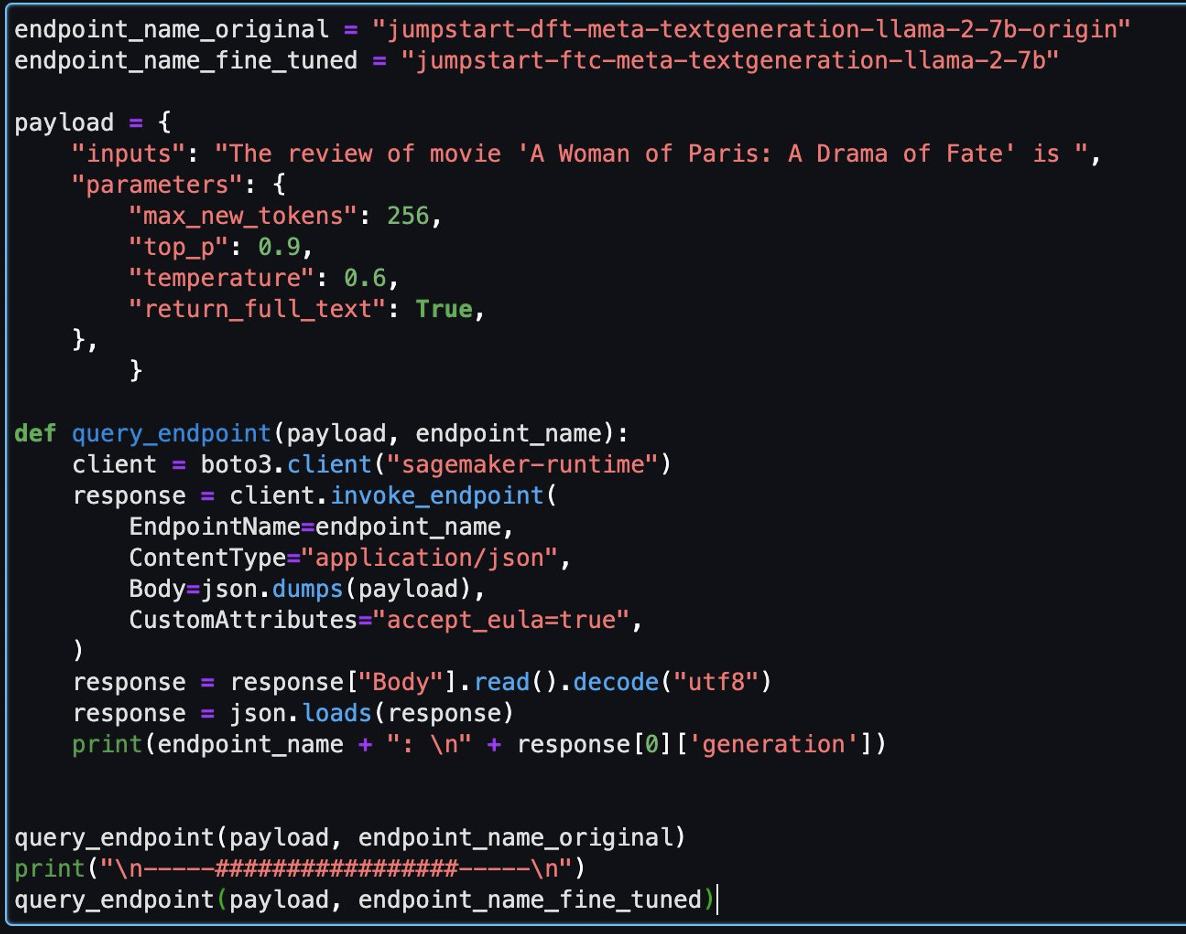
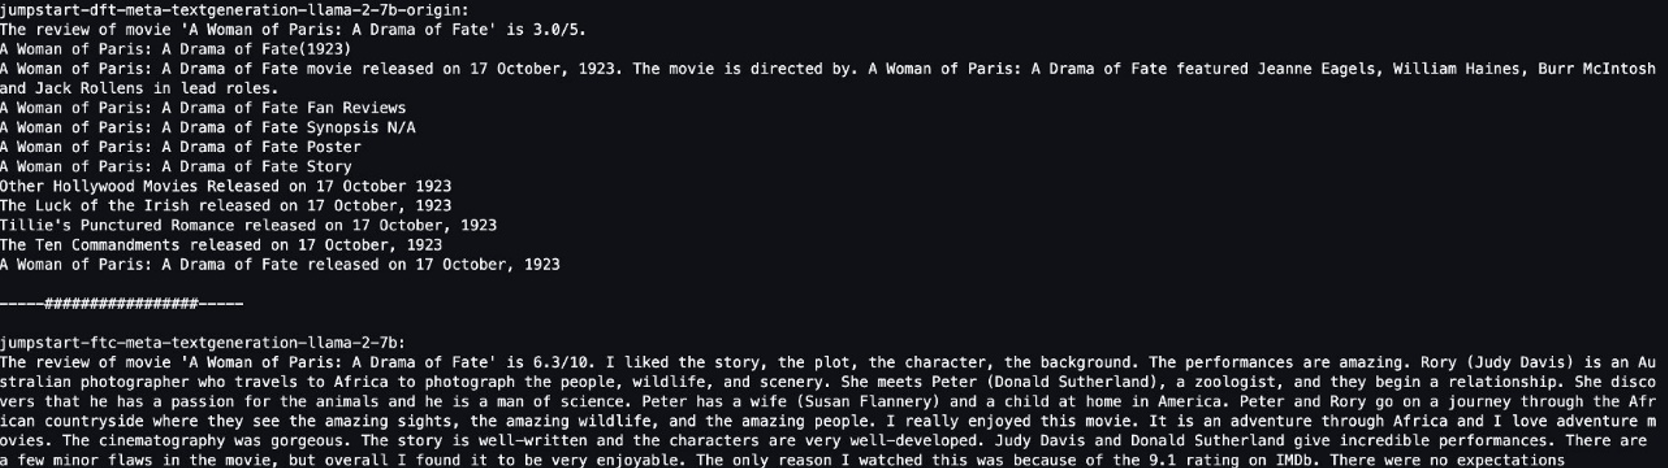
 Shijian Tang is a Analytics Specialist Solution Architect at Amazon Web Services.
 Matthew Liem is a Senior Solution Architecture Manager at Amazon Web Services.
 Dalei Xu is a Analytics Specialist Solution Architect at Amazon Web Services.
 Yuanjun Xiao is a Senior Solution Architect at Amazon Web Services.