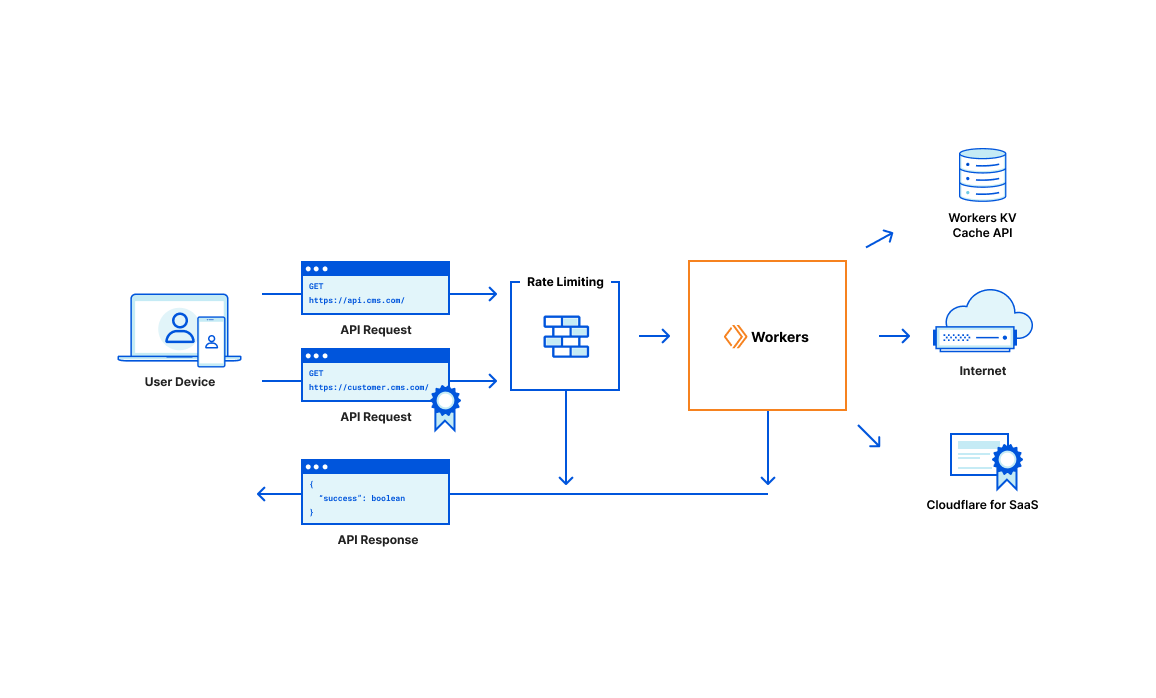
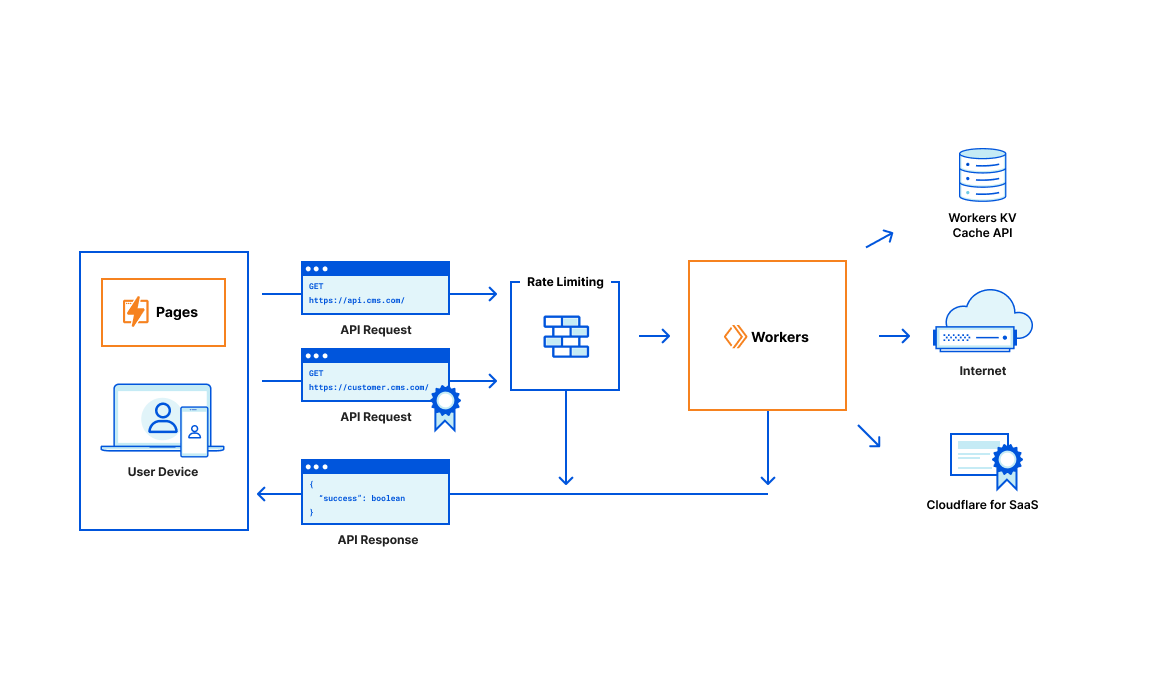
Handling payments inside your apps is crucial to building a business online. For many developers, the leading choice for handling payments is Stripe. Since my first encounter with Stripe about seven years ago, the service has evolved far beyond simple payment processing. In the e-commerce example application I shared last year, Stripe managed a complete seller marketplace, using the Connect product. Stripe’s product suite is great for developers looking to go beyond accepting payments.
Earlier versions of Stripe’s SDK had core Node.js dependencies, like many popular JavaScript packages. In Stripe’s case, it interacted directly with core Node.js libraries like net/http, to handle HTTP interactions. For Cloudflare Workers, a V8-based runtime, this meant that the official Stripe JS library didn’t work; you had to fall back to using Stripe’s (very well-documented) REST API. By doing so, you’d lose the benefits of using Stripe’s native JS library — things like automatic type-checking in your editor, and the simplicity of function calls like stripe.customers.create(), instead of manually constructed HTTP requests, to interact with Stripe’s various pieces of functionality.
We won’t stop until our users can import popular Node.js libraries seamlessly. This effort will be large-scale and ongoing for us, but we think it’s well worth it.
I’m excited to announce general availability for the stripe JS package for Cloudflare Workers. You can now use the native Stripe SDK directly in your projects! To get started, install stripe in your project: npm i stripe.
This also opens up a great opportunity for developers who have deployed sites to Cloudflare Pages to begin using Stripe right alongside their applications. With this week’s announcement of serverless function support in Cloudflare Pages, you can accept payments for your digital product, or handle subscriptions for your membership site, with a few lines of JavaScript added to your Pages project. There’s no additional configuration, and it scales automatically, just like your Pages site.
To showcase this, we’ve prepared an example open-source repository, showing how you can integrate Stripe Checkout into your Pages application. There’s no additional configuration needed — as we announced yesterday, Pages’ new Workers Functions features allows you to deploy infinitely-scalable functions just by adding a new functions folder to your project. See it in action at stripe.pages.dev, or check out the open-source repository on GitHub.
With the SDK installed, you can begin accepting payments directly in your applications. The below example shows how to initiate a new Checkout session and redirect to Stripe’s hosted checkout page:
With support for the Stripe SDK natively in Cloudflare Workers, you aren’t just limited to payment processing either. Any JavaScript example that’s currently in Stripe’s extensive documentation works directly in Workers, without needing to make any changes.
In particular, using Workers to handle the multitude of available Stripe webhooks means that you can get better visibility into how your existing projects are working, without needing to spin up any new infrastructure. The below example shows how you can securely validate incoming webhook requests to a Workers function, and perform business logic by parsing the data inside that webhook:
const Stripe = require("stripe");

const stripe = Stripe(STRIPE_API_KEY, {
  httpClient: Stripe.createFetchHttpClient()
});

export default {
  async fetch(request) {
    const body = await request.text()
    const sig = request.headers.get('stripe-signature')
    const event = stripe.webhooks.constructEvent(body, sig, secret)

    // Handle the event
    switch (event.type) {
      case 'payment_intent.succeeded':
        const paymentIntent = event.data.object;
        // Then define and call a method to handle the successful payment intent.
        // handlePaymentIntentSucceeded(paymentIntent);
        break;
      case 'payment_method.attached':
        const paymentMethod = event.data.object;
        // Then define and call a method to handle the successful attachment of a PaymentMethod.
        // handlePaymentMethodAttached(paymentMethod);
        break;
      // ... handle other event types
      default:
        console.log(`Unhandled event type ${event.type}`);
    }

    // Return a response to acknowledge receipt of the event
    return new Response(JSON.stringify({ received: true }), {
      headers: { 'Content-type': 'application/json' }
    })
  }
}
We’re also announcing a new Workers template in partnership with Stripe. The template will help you get up and running with Stripe and Workers, using our best practices.
In less than five minutes, you can begin accepting payments for your next digital product or membership business. You can also handle and validate incoming webhooks at the edge, from a single codebase. This comes with no upfront cost, server provisioning, or any of the standard scaling headaches. Take your serverless functions, deploy them to Cloudflare’s edge, and start making money!
“We’re big fans of Cloudflare Workers over here at Stripe. Between the wild performance at the edge and fantastic serverless development experience, we’re excited to see what novel ways you all use Stripe to make amazing apps.” — Brian Holt, Stripe
We’re thrilled with this incredible update to Stripe’s JavaScript SDK. We’re also excited to see what you’ll build with native Stripe support in Workers. Join our Discord server and share what you’ve built in the #what-i-built channel — get your invite here.
The Cloudflare documentation is a great resource when learning concepts, reviewing API usage notes, or when you’re in need of a concise snippet to illustrate those APIs or concepts. But, as comprehensive as it is, new users to the Cloudflare Workers platform must bridge a large gap to go from the introductory example snippets to a real, production-ready application. While some of this may be specific to Workers (as with any platform), developers everywhere are figuring out how applications should be built in a serverless world. Building large serverless applications entails a learning curve journey, regardless of a developer’s experience level.
At Cloudflare, we’re intimately aware of this because we also had to go through the same transition. Our engineers are world-class and expertfully design and craft products that compliment the distributed paradigm… but experts aren’t born overnight! We have been there, and we want to help jumpstart and aid others’ understanding.
With this in mind, we decided to do something unique to the industry: we are developing an example feature-complete SaaS application that will be built entirely on the Cloudflare stack. It is and will continue to be completely free, open-sourced on GitHub, and developed in public. This will be an incredible time as it can be used as a template for launching your own SaaS applications, too! In fact, you can clone the GitHub repository, update a few service tokens, and deploy the pre-built application to your own Cloudflare account within minutes!
Of course, examples and templates are great, but technologies and best practices never stop evolving. Cloudflare is no exception and is constantly iterating and introducing new products and product features. By extension, this requires the SaaS application to be a living example that evolves alongside the Workers platform — and this is part of our commitment.
|| Don’t miss out! Watch the project on GitHub to track its development progress and stay current with our latest changes and recommendations.
Application Overview
Now, aside from actually building the application, we needed to find a balance between picking an example SaaS application that is both complex enough to serve as a convincing case study and simple — or self-contained — enough so that developers can quickly dive in, follow the source, and understand the components involved and the reasons why and/or how they are used.
Ultimately we decided to build an example content management system (CMS) which, as an application archetype, has also transformed over the years. Traditionally, a CMS operated on rented hardware, which was home to a long-lived server that handled incoming requests and queried an SQL-like database in order to retrieve the requested content, render it to an HTML page, and repeat the process over and over again. WordPress was — and still is — a very common example of this approach.
Naturally, this application architecture was improved over the years: layers of caching were introduced, database schemas were redesigned to minimize the number of rows processed, and some frameworks began to skip the database entirely, preferring a build-step to render all content upfront as static HTML pages. (This is now known as “static-site generation” and is still a very popular approach.)
Today, in the serverless era, there are a number of “headless CMS” options available. These are made “headless” because they are not monolithic web servers that render HTML for each request. Instead, they offer API endpoints that will return the content as raw JSON data. This allows web developers to build completely custom templates for their website using whatever tools and/or frameworks they prefer. This approach grants an enormous amount of flexibility to the developer without losing the ability to organize their content, image assets, etc. WordPress, the seasoned veteran, is one of few that is able to offer a headless and a “headful” mode. Other headless choices, like Sanity.io and Contentful, are also quite popular.
The CMS application model is a great case study for our open-source example. One of the primary tenets of an edge-first design is that content should be made available as close as physically possible to the users asking for it. And the serverless architecture means that there’s no longer — or should not be — a single point of failure. These both directly benefit the CMS archetype and, when implemented, will yield clear performance gains.
Current Progress
Before diving into the roadmap and explaining how this project will progress, it’s important to call out that this project has already been — and will continue to be — an ongoing effort! Today, you can find the project on GitHub and inspect the work that’s already been completed. As of now, the application already combines Workers, Workers KV, Cloudflare for SaaS, and Rate Limiting with Pages and Durable Objects additions to come in later milestones.
Phase 1 (see below) is nearing completion and, when finished, will mark the end of a very significant milestone. A new update to this blog post series will be issued, covering the highlights and technical overview of the project so far. This is important and immediately useful because on its own, Phase 1 qualifies for a successful, full-stack application.
Development Milestones
The CMS application will progress in milestones. We have already released the project and will continue to build upon it in accordance with the roadmap (below). GitHub stargazers will be able to keep tabs on its progress, or at the very least, only subscribe to updates for the milestones they’re interested in following.
Each milestone is a sizable checkpoint on its own. As you’ll see below, the project roadmap is planned in a way such that each phase adds a considerable amount of new features and/or integrates with a new Cloudflare product. At every point, the application will remain functional and maintain a live, interactive demo to immediately demonstrate the latest functionality to passersby.
This format is chosen because it’s how real applications — and real products — are developed. Our goal is to ensure that the GitHub repository is never out of date. And, because of the development structure, one may always traverse the list of past milestones to review the changes that were necessary to migrate X or how product Y was integrated.
|| Note: Visit the GitHub milestones to view more details and to subscribe for updates. There is so much more than can be listed here.
Phase 1 – JSON API
The project must begin with some API endpoints to start managing and manipulating data. Using Workers and Workers KV, the work within this milestone will focus on building a robust JSON API that handles the core functionality that the rest of the application will need.
There is no HTML, CSS, or client-side JavaScript involved in this phase. Instead, work here should focus solely on the data: how it’s accessed, how models relate to one another, and how best to structure and store these relationships within Workers KV. For example, individuals should be able to create and manage workspaces that belong to their personal user accounts or to the organization(s) that they belong to.
Additionally, when creating content, the document should be validated against an existing schema that the document was assigned. This feature is critical in any CMS platform that plans to handle thousands of documents within a workspace. Without it, there’s very little confidence that your contents’ JSON representation is consistently structured.
A number of other features are planned — subscription management and invoicing through Stripe, sending transactional emails through SendGrid, and assigning vanity domains to workspaces through Cloudflare for SaaS. Finally, of course, the standard house-keeping tasks will be set up. This includes continuous integration (CI) with API testing and automated, continuous deployments (CD).
By the end of this phase, the project will exist as a collection of API endpoints that, on its own, is a complete application. While it may only be accessible through curl commands — or any other preferred method for manually constructing HTTP requests, the completion of Phase 1 already qualifies the project as a full-stack application and could serve a real-world SaaS product.
Additionally, the repository will include all the best practices for writing tests, automating deployments, and organizing the source in a way for long-term growth and maintenance. And, because we started with the JSON API, the project is immediately useful and capable of integrating with your existing build tools and frameworks. In other words, stargazers could deploy the project to their own accounts as their own personalized Headless CMS. Perhaps some of you will build Gatsby or Eleventy plugins — if you do, please let us know!
Phase 2 — Dashboard UI
As fun as curl may be, most people prefer some form of visual interface they can interact with. This phase will be all about assembling a frontend to serve as the CMS application’s dashboard.
We will use Svelte, a JavaScript framework for building user interfaces. While not everyone may enjoy or agree with this decision, the templating syntax resembles standard HTML markup, which will allow non-frontend developers to follow along and gauge what’s going on.
Svelte will be paired with Tailwind CSS for the design system. Tailwind is a very popular, utility-first CSS framework that allows developers to compose styles through predefined, reusable HTML ”class” names.
The result will be a single-page application (SPA) and will be hosted on Cloudflare Pages. This means that, out of the box, the dashboard will be able to take advantage of Access-protected preview deployments, instant rollbacks, automated deployments, comprehensive analytics, and more.
Finally, now that Pages integrates with Workers directly, the JSON API from Phase 1 will migrate into a new repository structure. While this may seem like an innocent refactor, it actually unlocks an incredible set of features for the JSON API: Access-protected preview deployments, instant rollbacks, and automated deployments. Yes — these are the same Pages features mentioned above! This is amazing because it means that our API is continuously and atomically versioned, allowing its development to continue safely alongside the client dashboard that depends on it. In other words, there is zero risk of the API and the dashboard diverging, which would have allowed their expectations of one another to misalign. Instant rollbacks will also apply to the API since the entire application operates as a single Pages unit.
The previous phase will have built the core SaaS product functionality, but completing this phase will make it feel like a real-world product that can be launched and used on a daily basis. In fact, the end of Phase 2 marks the application as a possible contender in the Headless CMS service space.
Phase 3 — Article Edge-Rendering
The previous phases are focused on assembling a minimum viable Headless CMS product, but Phase 3 looks to grow outside this archetypal box. This will happen by allowing the application to render HTML web pages by injecting the JSON content into predefined templates.
Like WordPress, the CMS application should allow its users to choose whether they want to continue using the “headless” feature or enlist the complete template engine. Should they opt for HTML output, the Cloudflare project will only include a few premade templates that a user may select from — but, of course, this can be customized in your own projects.
Even though this phase reintroduces the monolithic CMS archetype, it’s a significantly safer, faster, and more resilient architecture than the single, all-in-one server of yesteryear. The CMS contents will still be distributed around the world, close to the customers’ readers — but now, the content can be rendered from anywhere in the world at extremely low latencies, too.
Phase 4 — Feature Upgrades
At this stage, the application is — for the most part — complete. It’s functional, looks nice, performs well globally, and can be used in two very distinct ways.
In the context of a real SaaS product, development begins to shift towards adding new features that excite users or towards maintenance health of the project. For example, Phase 4 will utilize Durable Objects to introduce a document editor that allows multiple users to edit the same document in a real-time, collaborative environment.
It’s also very likely that Cloudflare R2 Storage will be introduced as a backend for media assets, allowing users to upload and manage images within a workspace. Or perhaps we decide to use Cloudflare Images for this and R2 is used for importing and exporting content backups.
As you may expect, this milestone is full of unknowns, but that’s because the future holds unlimited possibilities. The project will continue to evolve and expand with Cloudflare and with time.
Of course, if you have ideas or suggestions for features, start a discussion with us on GitHub. We would love to hear from you!
Next Steps
This was the introductory post of (what will be) an ongoing series. When each milestone is completed, we will publish a new post in this series with a retrospective and with technical walkthroughs of key aspects from that chapter’s work.
We’re at the beginning of an exciting journey, and we hope you’re as interested as we are!
You can show your support by starring or following the project on GitHub. All releases, discussions, and milestone tracking will reside within the repository. The next generation of SaaS applications will be built on Cloudflare — subscribe and dive in early!
Historically, building video applications has been very difficult. There’s a lot of complicated tech behind recording, encoding, and playing videos. Luckily, Cloudflare Stream abstracts all the difficult parts away, so you can build custom video and streaming applications easily. Let’s look at how we can combine Cloudflare Stream, Access, Pages, and Workers to create a high-performance video application with very little code.
Today, we’re going to build a video application inspired by Cloudflare TV. We’ll have user authentication and the ability for administrators to upload recorded videos or livestream new content. Think about being able to build your own YouTube or Twitch using Cloudflare services!
Fetching a list of videos
On the main page of our application, we want to display a list of all videos. The videos are uploaded and stored with Cloudflare Stream, but more on that later! This code could be changed to display only the “trending” videos or a selection of videos chosen for each user. For now, we’ll use the search API and pass in an empty string to return all.
We’ll go through each video, filter out any private videos, and pull out the metadata we need, such as the thumbnail URL, ID, and created date.
Playing the videos
To allow users to play videos from your application, they need to be public, or you’ll have to sign each request. Marking your videos as public makes this process easier. However, there are many reasons you might want to control access to your videos. If you want users to log in before they play them or the ability to limit access in any way, mark them as private and use signed URLs to control access. You can find more information about securing your videos here.
If you are testing your application locally or expect to have fewer than 10,000 requests per day, you can call the /token endpoint to generate a signed token. If you expect more than 10,000 requests per day, sign your own tokens as we do here using JSON Web Tokens.
Allowing users to upload videos
The next step is to build out an admin page where users can upload their videos. You can find documentation on allowing user uploads here.
This process is made easy with the Cloudflare Stream API. You use your API token and account ID to generate a unique, one-time upload URL. Just make sure your token has the Stream:Edit permission. We hook into all POST requests from our application and return the generated upload URL.
export const cfTeamsAccessAuthMiddleware = async ({request, data, env, next}) => {
    try {
        const userEmail = request.headers.get("cf-access-authenticated-user-email")

        if (!userEmail) {
            throw new Error("User not found, make sure application is behind Cloudflare Access")
        }

        // Pass user info to next handlers
        data.user = {
            email: userEmail
        }

        return next()
    } catch (e) {
        return new Response(e.toString(), {status: 401})
    }
}

export const onRequest = [
    cfTeamsAccessAuthMiddleware
]
The admin page contains a form allowing users to drag and drop or upload videos from their computers. When a logged-in user hits submit on the upload form, the application generates a unique URL and then posts the FormData to it. This code would work well for building a video sharing site or with any application that allows user-generated content.
You can add a livestreaming section to your application as well, using Stream Live in conjunction with the techniques we’ve already covered. You could allow logged-in users to start a broadcast and then allow other logged-in users, or even the public, to watch it in real-time! The streams will automatically save to your account, so they can be viewed immediately after the broadcast finishes in the main section of your application.
Securing our app with middleware
We put all authenticated pages behind this middleware function. It checks the request headers to make sure the user is sending a valid authenticated user email.
export const cfTeamsAccessAuthMiddleware = async ({request, data, env, next}) => {
    try {
        const userEmail = request.headers.get("cf-access-authenticated-user-email")

        if (!userEmail) {
            throw new Error("User not found, make sure application is behind Cloudflare Access")
        }

        // Pass user info to next handlers
        data.user = {
            email: userEmail
        }

        return next()
    } catch (e) {
        return new Response(e.toString(), {status: 401})
    }
}

export const onRequest = [
    cfTeamsAccessAuthMiddleware
]
Putting it all together with Pages
We have Cloudflare Access controlling our log-in flow. We use the Stream APIs to manage uploading, displaying, and watching videos. We use Workers for managing fetch requests and handling API calls. Now it’s time to tie it all together using Cloudflare Pages!
Pages provides an easy way to deploy and host static websites. But now, Pages seamlessly integrates with the Workers platform (link to announcement post). With this new integration, we can deploy this entire application with a single, readable repository.
Controlling access
Some applications are better public; others contain sensitive data and should be restricted to specific users. The main page is public for this application, and we’ve used Cloudflare Access to limit the admin page to employees. You could just as easily use Access to protect the entire application if you’re building an internal learning service or even if you want to beta launch a new site!
When a user clicks the admin link on our demo site, they will be prompted for an email address. If they enter a valid Cloudflare email, the application will send them an access code. Otherwise, they won’t be able to access that page.
Check out the source code and get started building your own video application today!
Our mission is to enable developers to build their applications, end to end, on our platform, and ruthlessly eliminate limitations that may get in the way. Today, we’re excited to announce you can build large, data-intensive applications on our network, all without breaking the bank; starting today, we’re dropping egress fees to zero.
More Affordable: No Egress Fees
Building more on any platform historically comes with a caveat — high data transfer cost. These costs often come in the form of egress fees. Especially in the case of data intensive workloads, egress data transfer costs can come at a high premium, depending on the provider.
What exactly are data egress fees? They are the costs of retrieving data from a cloud provider. Cloud infrastructure providers generally pay for bandwidth based on capacity, but often bill customers based on the amount of data transferred. Curious to learn more about what this means for end users? We recently wrote an analysis of AWS’ Egregious Egress — a good read if you would like to learn more about the ‘Hotel California’ model AWS has spun up. Effectively, data egress fees lock you into their platform, making you choose your provider based not on which provider has the best infrastructure for your use case, but instead choosing the provider where your data resides.
At Cloudflare, we’re working to flip the script for our customers. Our recently announced R2 Storage waives the data egress fees other providers implement for similar products. Cloudflare is a founding member of the Bandwidth Alliance, aiming to help our mutual customers overcome these data transfer fees.
We’re keeping true to our mission and, effective immediately, dropping all Egress Data Transfer fees associated with Workers Unbound and Durable Objects. If you’re using Workers Unbound today, your next bill will no longer include Egress Data Transfer fees. If you’re not using Unbound yet, now is a great time to experiment. With Workers Unbound, get access to longer CPU time limits and pay only for what you use, and don’t worry about the data transfer cost. When paired with Bandwidth Alliance partners, this is a cost-effective solution for any data intensive workloads.
More Unbound: 15 Minutes
This week has been about defining what the future of computing is going to look like. Workers are great for your latency sensitive workloads, with zero-milliseconds cold start times, fast global deployment, and the power of Cloudflare’s network. But Workers are not limited to lightweight tasks — we want you to run your heavy workloads on our platform as well. That’s why we’re announcing you can now use up to 15 minutes of CPU time on your Workers! You can run your most compute-intensive tasks on Workers using Cron Triggers. To get started, head to the Settings tab in your Worker and select the ‘Unbound’ usage model.
Once you’ve confirmed your Usage Model is Unbound, switch to the Triggers tab and click Add Cron Trigger. You’ll see a ‘Maximum Duration’ is listed, indicating whether your schedule is eligible for 15 Minute workloads.
Wait, there’s more (literally!)
That’s not all. As a platform, it is validating to see our customers want to grow even more with us, and we’ve been working to address these restrictions. That’s why, starting today, all customers will be allowed to deploy up to 100 Worker scripts. With the introduction of Services, that represents up to 100 environments per account. This higher limit will allow our customers to migrate more use cases to the Workers platform.
We’re also delighted to announce that, alongside this increase, the Workers platform will plan to support scripts larger in size. This increase will allow developers to build Workers with more libraries and new possibilities, like running Golang with WASM. Check out an example of esbuild running on a Worker, in a script that’s just over 2MB compressed. If you’re interested in larger script sizes, sign up here.
The future of cloud computing is here, and it’s on Cloudflare. Workers has always been the secure, fast serverless offering, and has recently been named a leader in the space. Now, it is even more affordable and flexible too. We can’t wait to see what ambitious projects our customers build. Developers are now better positioned than ever to deploy large and complex applications on Cloudflare. Excited to build using Workers, or get engaged with the community? Join our Discord server to keep up with the latest on Cloudflare Workers.
Next up on the Developer Spotlight is another favourite of mine. Today’s post is by Jacob Hands. Jacob operates TriTails Premium Beef, which is an online store for meat, a very perishable good. So he has a lot of unique challenges when it comes to shipping. To deal with their growth, Jacob, a developer by trade, turned to Airtable and Cloudflare Workers to automate a lot of their workflow.
One of Jacob’s quotes is one of my favourites:
“Sure, Cloudflare Workers allows you to scale to billions of requests per day, but it is also awesome for a few hundred requests a day.”
Here is Jacob talking about how it only took him a few days to put together a fully customised workflow tool by integrating Airtable and Workers. And how it saves them multiple hours every single day.
Shipping Requirements
Working at a new e-commerce business shipping perishable goods has several challenges as operations scale up. One of our biggest challenges is that daily shipping throughput is limited. Partly because of a small workspace, limiting how many employees can simultaneously pack orders, and also because despite having a requested pickup time with UPS, they often show up hours early, requiring packers to stop and scramble to meet them before they leave. Packing is also time-consuming because it’s a game of Tetris getting all products to fit with enough dry ice to keep it frozen.
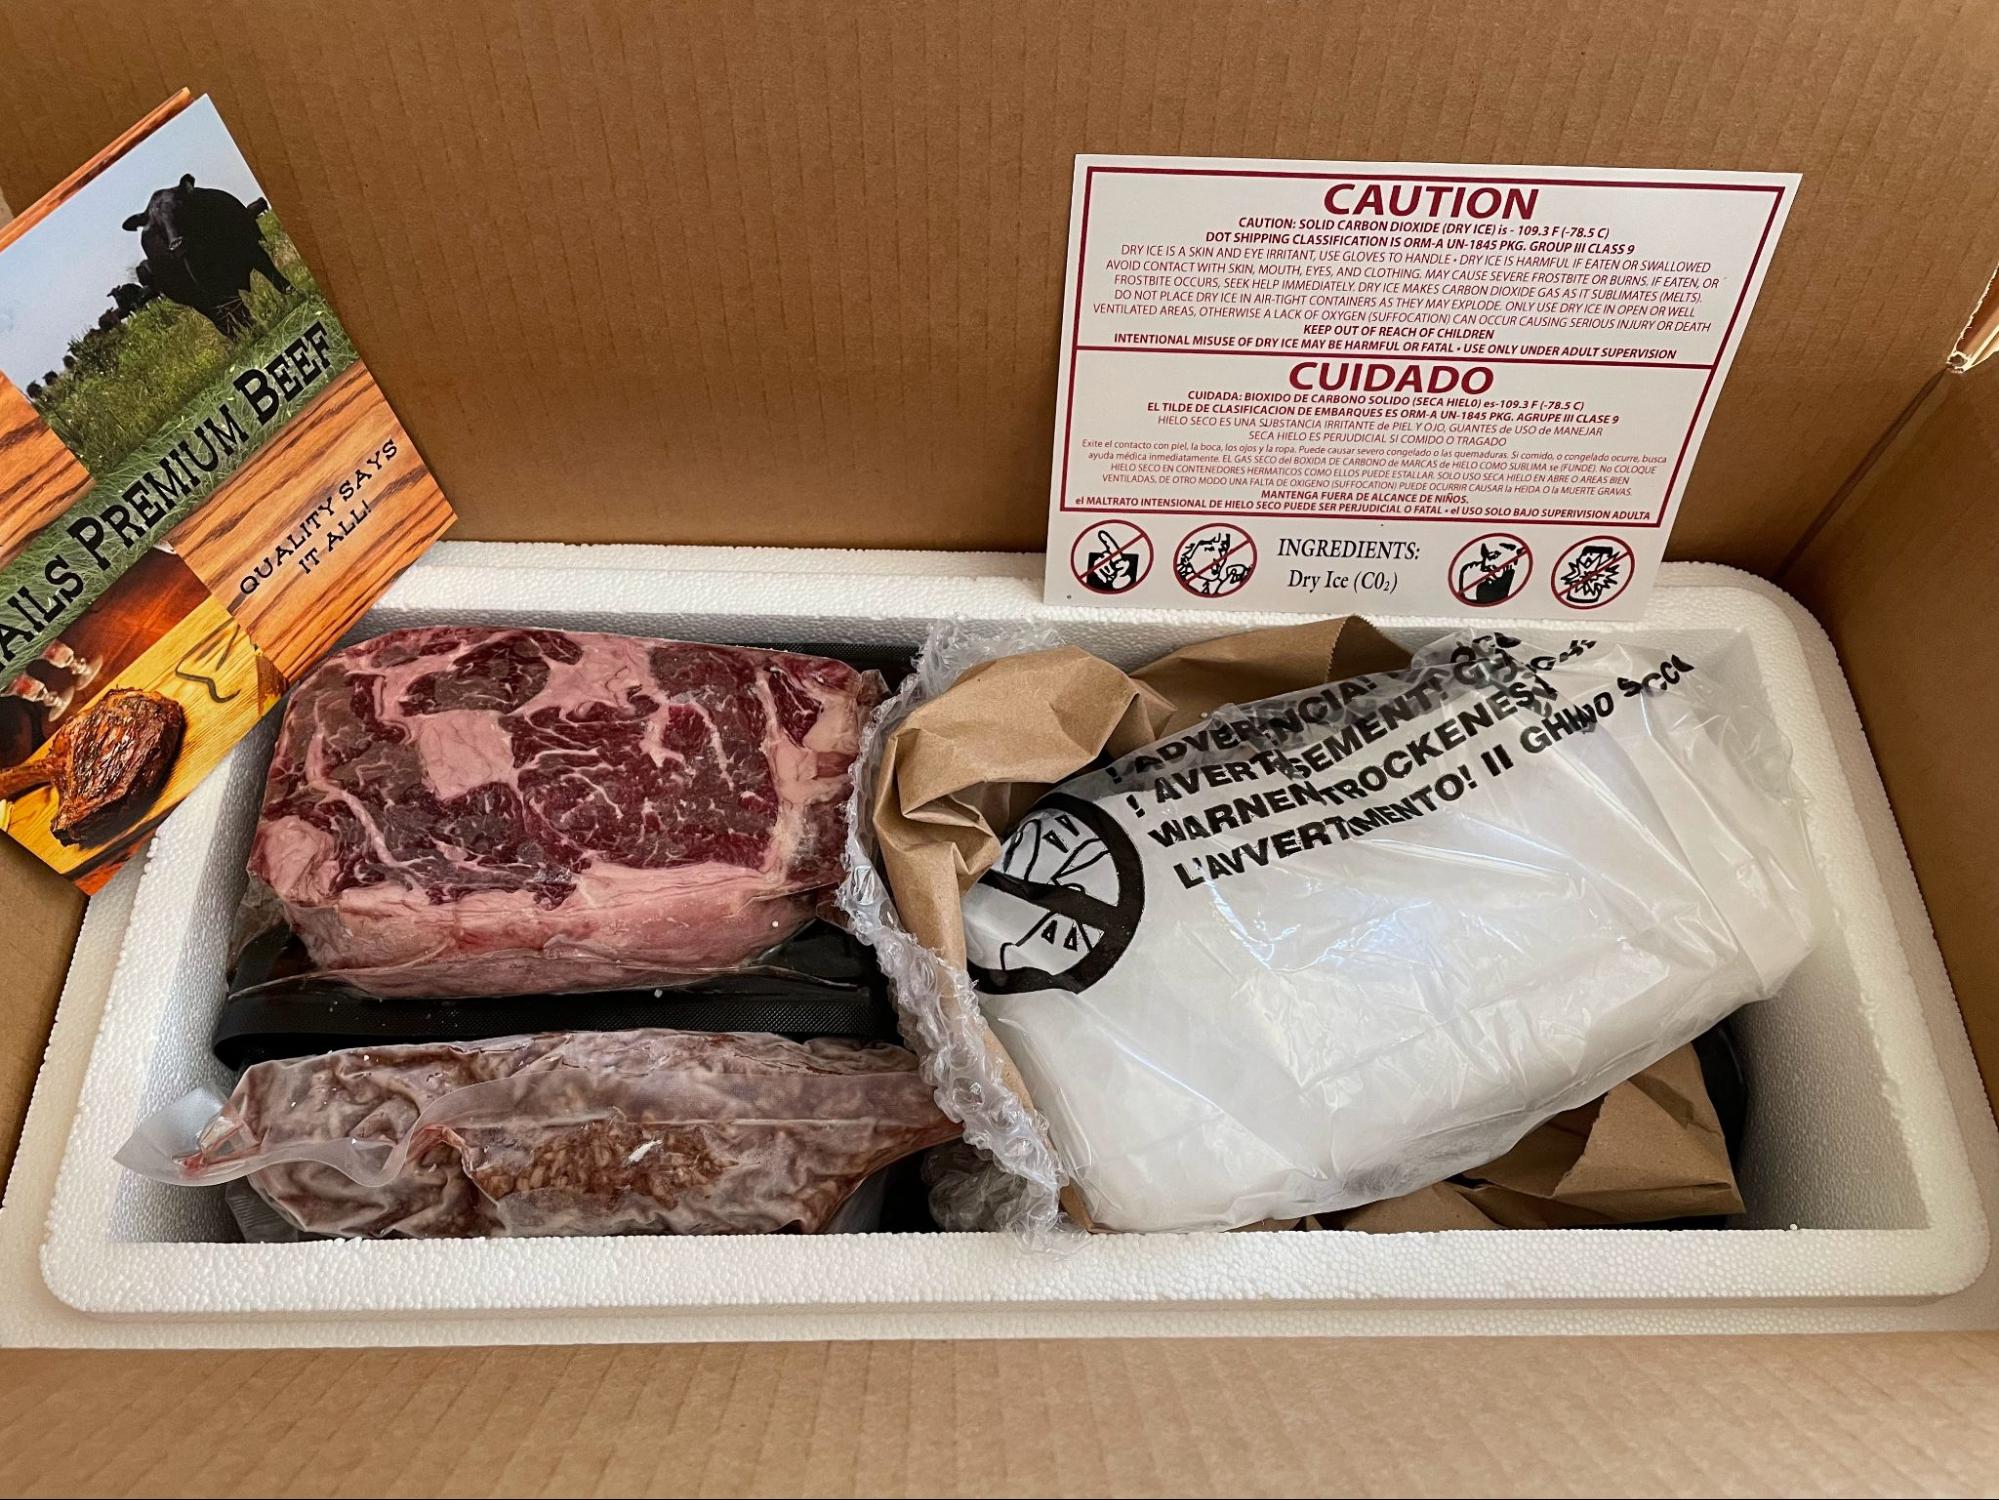
This is what a regular box looks like:
Ensuring time-in-transit stays as low as possible is critical for ensuring that products stay frozen when arriving at the customer’s doorstep. Because of this requirement, avoiding packages staying in transit during the weekend is a must. We learned that the hard way after a package got delayed by a day, which wouldn’t have been too bad, but that meant it stayed in a sorting centre over the weekend, which wasn’t as pleasant.
Luckily, we caught it on time, and we were able to send a replacement set of steaks overnight and save a dinner party. But after that, we started triaging our orders to make sure that the correct packages were shipped at the right time.
Order Triage, The Hard Way
In the early days, we could pack orders after lunch and be done in an hour, but as we grew we needed to be careful about what, when, and how we ship. First, all open orders were copied to a Google Sheet. Next, the time-in-transit was manually checked for each order and added to the sheet. The sheet was then sorted by transit time (with paid priority air at the top), and each set of orders was separated into groups. Finally, the Google Sheet was printed for the packing team to work through.
Transit times are so crucial to the shipment process that they need to be on each packing slip so that the packing team knows how much dry ice and packaging each order needs. So the transit times were typed into each packing slip in Adobe Acrobat before printing. While this is a very tedious process, it is vital to ensure that each package is packed according to what they need to arrive in good condition.
Once the packing team would finish packing orders, the box weights and sizes were added to the Google Sheet based on the worksheet filled out by the packers. Next, each order label was created, individually copying weights and sizes from the Google Sheet to ShipStation, the application we use to manage logistics with our providers. Finally, the packages would be picked up and started their journey to the customer’s doorstep.
This process worked fine for ten orders, but as operations scaled up, triaging and organizing the orders became a full-time job, checking and double-checking that everything was entered correctly and that no human mistakes occurred (spoiler, they still happened!)
Automation
At first, I just wanted to automate the most tedious step: calculating transit times. This process took so long that it hindered how early the packing team could start packing orders, further limiting our throughput. Cloudflare Workers are so easy to use and get running quickly, so they seemed like a great place to start. The plan was to use =IMPORTDATA(order) in Google Sheets and eliminate that step in the process.
Automating just one thing is powerful, and it opened a flood of ideas about how our workflow could further be improved. With the first 30 minutes of daily work automated, what else could be done? That’s when I set out to automate as much of the workflow as possible, excited about the possibilities.
Triaging the Triaging
Problem-solving is often about figuring out what to prioritize, and automating this workflow is no different. Our order triaging process has many steps, and setting out to automate the entire thing at once wasn’t possible because of the limited blocks of time to work on it. Instead, I decided to only solve the highest priority problems, one step at a time. Triaging the triaging process helped me build everything needed to automate an entire workflow without it ever feeling overwhelming, and gaining efficiency each step along the way.
With the time-in-transit calculation API working, the next part I automated was getting the orders that need shipping from Shopify via the API instead of copy-pasting every time. This is where the limits of Google Sheets started to become apparent. While automation can be done in Sheets, it can quickly become a black box full of hacks. So it was time to move to a better platform, but which one?
While I had often heard of Airtable and played with it a few times since it launched in 2012, the pricing and limitations never seemed to fit any of my use cases. But with the little amount of data we needed to store at any one time, it seemed worth trying since it has an easy-to-use API and supports strict cell formats, which is much harder to do in Sheets. Airtable has an intuitive UI, and it is easy to create custom fields for each type of data needed.
Once I found out Airtable had a built-in Scripting app, it was obvious this was the right tool for the job.
Building Airtable Scripting Apps
Airtable Scripting is a powerful tool for building functionality directly within Airtable using JavaScript. Unfortunately, there are some limitations. For example, it isn’t possible to share code between different instances of the Scripting App without copying and pasting. There’s also no source control so reverting changes relies on the Undo button.
Cloudflare Workers, on the other hand, is a full developer platform. You can easily use source control, and it has a great developer experience with Wrangler and Miniflare, so testing and deploying is fast and seamless.
Airtable Scripting and Cloudflare Workers work together beautifully. Building APIs on Workers allows more complex tasks to run on the Cloudflare network. These APIs are then fetched by Airtable scripts, solving the code-sharing issue and speeding up development.
Shopify Order Importing
First, we needed to import orders from Shopify into Airtable. The API endpoint I created in Workers goes through all open orders and figures out which ones should be shipped this week. The orders are then cached in the Workers Cache API, so we can request this endpoint as much as needed without hitting Shopify API’s limits.
From there, the Airtable Scripting app checks the transit time for each order using our Workers API that makes calls to Shippo (a multi-carrier shipping API) to get time-in-transit estimates for the carrier. Finally, each row in Airtable is updated with the respective transit times, automatically sorted with priority paid air at the top, followed by the longest to the shortest transit times.
Going from an entirely manual process of getting a list of triaged orders in 45 minutes to clicking a button and having Airtable and Workers do it all for me in seconds was one of the most significant “lightbulb” moments I’ve ever had programming.
Printing Packing Slips in Order
The next big thing to tackle was the printing of packing slips. They need to be printed in the triaged order rather than in chronological order. To do so, this manually required searching for each order, but now a button in Airtable generates links to Shopify search with each batch of orders prefilled.
Printing the Order Worksheet
Of course, we just couldn’t stop there.
To keep track of orders as they are packed, we use a printed worksheet with all orders listed and columns for each order’s box size and weight. Unfortunately, Airtable does not have a good way to customize the printout of a table.
Ironically, this brought us back to Google Sheets! Since Sheets is the easiest way to format a table, it seemed like the best choice. But copying data from Airtable to Sheets is tedious. Instead, I created an API endpoint in Workers to get the data from Airtable and format it as a CSV the way we need it to look when printing. From Sheets, the IMPORTDATA function imports the day’s orders automatically when opened, ready for printing.
Sending Package Details to ShipStation
Once the packing team has finished packing and filling out the shipment worksheet, box size and weights are entered into Airtable for each order. Rather than typing these details also into ShipStation, I built an endpoint in our Workers API to set the weight and size using the ShipStation API. ShipStation order updates are done based on the ID of the order. The script first lists all open orders and then writes the order name and ID mapping for all open orders to Workers KV so that future requests to this API can avoid the ShipStation list API, which is slow and has strict limits.
Next, I built another Airtable script to send the details of each box to this API. In addition to setting the weight and size, the order is also tagged with today’s date, making it easy to identify what orders in ShipStation are ready to be labeled. Finally, the labels are created and printed in ShipStation in bulk and applied to their respective packages.
Putting it all together
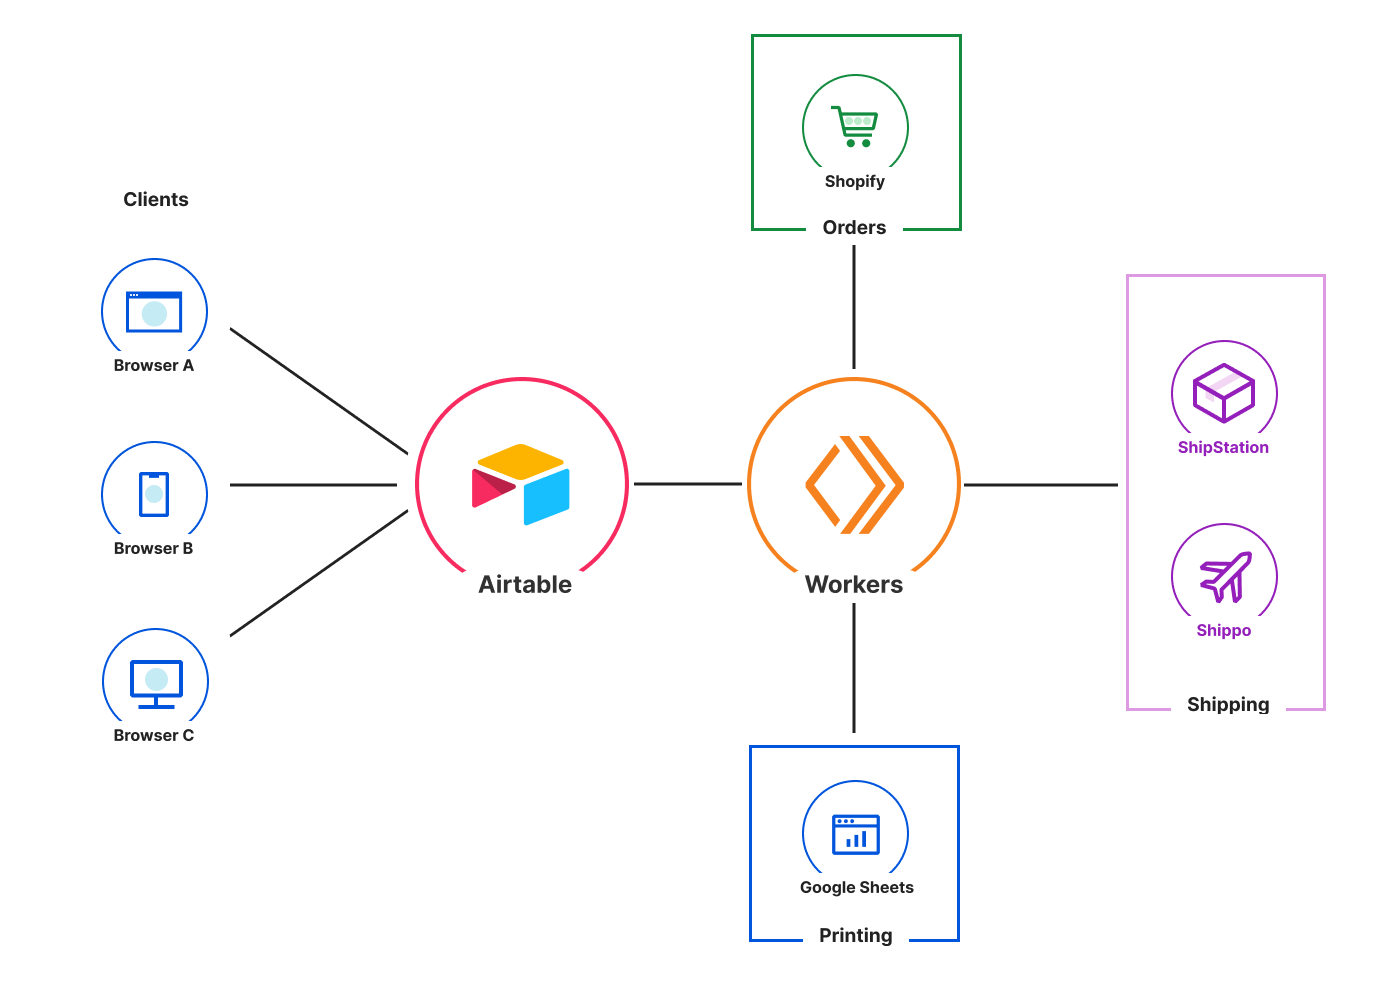
So an overview of the entire system looks like this. All clients connect to Airtable and Airtable makes calls out to the Worker APIs which connect and coordinates between all third party APIs.
Why Workers and Airtable Work Well Together
While it might have been possible to build this entire workflow in Airtable, integrating Workers has made the process much easier to build, test, and reuse code both between Airtable scripts and other platforms.
Development Experience
The Airtable Scripting app makes it quick and easy to build scripts that work with the data stored in Airtable, with a decent editor and autocomplete, but it is hard to build more complex scripts in it.
Funnily enough for this project, latency and scaling weren’t all that important. But Cloudflare Workers makes development and testing incredibly easy: no excessive configuration or deployment pipelines.
Reliability and Security
We are running a business and having to babysit servers is a massive distraction that we certainly don’t need. With Workers being fully serverless I never have to worry about anything breaking because a server is down.
And we can safely store all our secrets needed to access all third-party systems with Cloudflare, with the secret environments variables. Making sure those tokens and keys are all fully encrypted and secure.
Airtable is a great database and UI in one
Building UI’s around data entry and visualisation takes a lot of time and resources. By utilizing Airtable, I built out an entire workflow without ever touching HTML, let alone front-end frameworks. Instead, I could focus solely on core business logic. Airtable’s dashboard feature also allows building reports with high-level overviews of the types of packages being sent, helping us forecast future packing supplies needed.
While building workflows in spreadsheets can feel like a hack when custom scripting gets involved, Airtable is the opposite. The extensibility and good UX have made Airtable a great tool to use going forward.
Improvements Going Forward
Now that we had the basics covered, I noticed one of the most powerful things about this setup: how easy it was to add features. I started noticing minor issues with the workflow that could be improved. For example, when an order has to be split into multiple packages, the row in Airtable has to be duplicated and have a suffix added to the order number for each order. Automating order splitting was not a priority previously, but it quickly became one of the most time-consuming parts of the process. Thirty minutes later, every row had a “Split order” button, built with another Airtable script.
Another issue was when a customer was not going to be home on a Wednesday, which meant that if the order got shipped on Monday, it would go bad sitting on their doorstep. Thankfully, adding an optional minimum ship date tag to the Workers API that gets shippable orders was quick and easy. Now, our sales team can add tags for minimum ship dates when customers are not home, and the rest of the workflow will automatically take it into account when deciding what to ship.
Conclusion
Many businesses are turning to Workers for their incredible performance and scaling to millions or billions of requests, but we couldn’t be happier with how much value we get with the few hundred Workers requests we do every day.
Cloudflare Workers, especially in combination with tools like Airtable, make it really easy to create your own internal tool, built to your exact specifications. Which will bring this capability to so many more businesses.
Cloudflare is not affiliated with Formagrid, Inc., dba Airtable. The views and opinions expressed in this blog post are solely those of the guest author and do not necessarily represent those of Cloudflare, Inc.
Today we’re launching the Cloudflare Developer Expert Program: an initiative to support and recognize our VIP users who build with Workers, Pages, and the entire Cloudflare developer ecosystem.
A Cloudflare Developer Expert is an early adopter of new releases, a frequent participant in feedback sessions, and an evangelist for Cloudflare products made for the larger developer community.
But first, what are the benefits of becoming a Cloudflare Developer Expert?
Early access to features (e.g., private betas)
Admission to a private community of power users
Routine calls with product managers, engineers, and developer advocates
Sponsorships for OSS work
Our best swag, of course
We have already sent invites to our first batch of power users, but if you’d like to join or want to nominate a developer, please fill out this form.
Why We Made This Program
We ship very quickly at Cloudflare.
This is because we want feedback early in development, allowing users to challenge our assumptions and validate what we’re building. In the Workers team, this strategy has been very successful.
For example, we began beta testing custom builds for Wrangler (our CLI tool) that allow you to run any JavaScript bundler you want. This was a huge release because it introduced the ES Modules syntax for the first time in Workers, significantly increasing the number of usable JavaScript packages and libraries. To get feedback before public release, we opened a private Discord channel and invited around 50 users for testing.
We were blown away by the feedback.
Our users quickly discovered edge cases that weren’t working, such as needing support for Workers Unbound. This made it easy for us to prioritize what to fix before GA. We also discovered actionable steps to improve documentation.
“The Workers team wanted our input early on for such a big release, and it really shows how seriously they’re taking developer experience,” said James Ross, CTO of Nodecraft.
After seeing the success of this small group of users, we figured it was time to make this a regular part of development.
We threw together a list of users, sent NDAs, and opened a private Discord channel for one of our biggest releases of the year: running functions directly on Cloudflare Pages.
“We’re able to ship this feature more quickly and confidently because of feedback in our Discord,” said Nevi Shah, product manager for Cloudflare Pages. “Users let us know quickly what can be better and what features they need first.”
Developers, Developers, Developers
Back in April, we launched our first Developer Week with a central focus: how to get developers to build more on Cloudflare. This included exciting releases like Cloudflare Pages and the Durable Objects open beta.
Since then, after receiving so much feedback in our Discord and other channels, we learned developers either expect their code to automatically run on Cloudflare’s infrastructure (Cloudflare Pages), or, if it’s a new technology (such as Durable Objects) they want as much direct guidance as possible to reliably get up and running. We realized involving users earlier in development allowed us to support more happy paths.
And since developers like doing things their own way, we aim to support as many happy paths as possible on our platform.
“I started developing with Cloudflare Workers shortly after it was announced. Over that time, Cloudflare has only increased its emphasis on developer experience,” said David Barratt, staff software engineer at Drizly. “The Cloudflare Developer Expert Program has been a fantastic way to have a quick feedback loop between the developers who have a lot of experience using the platform and the developers building that platform.”
Apply now!
If you are a developer who deploys with Workers, Pages, and our other tools, we want you to apply! We’re hoping to review applicants with experience deploying to production with our developer tools.
And again, Cloudflare Developer Experts get special, special care from our team.
To apply for the Cloudflare Developer Expert Program, fill out this form.
When we announced Cloudflare Pages as generally available in April, we promised you it was just the beginning. The journey of our platform started with support for static sites with small bits of dynamic functionality like setting redirects and custom headers. But we wanted to give even more power to you and your teams to begin building the unimaginable. We envisioned a future where your entire application — frontend, APIs, storage, data — could all be deployed with a single commit, easily testable in staging and requiring a single merge to deploy to production. So in the spirit of “Full Stack” Week, we’re bringing you the tools to do just that.
Welcome to the future, everyone. We’re thrilled to announce that Pages is now a Full Stack platform with help from But how?
Cloudflare Workers provides a serverless execution environment that allows you to create entirely new applications or augment existing ones without configuring or maintaining infrastructure. Before today, it was possible to connect Workers to a Pages project—installing Wrangler and manually deploying a Worker by writing your app in both Pages and Workers. But we didn’t just want “possible”, we wanted something that came as second nature to you so you wouldn’t have to think twice about adding dynamic functionality to your site.
How it works
By using your repo’s filesystem convention and exporting one or more function handlers, Pages can leverage Workers to deploy serverless functions on your behalf. To begin, simply add a ./functions directory in the root of your project, and inside a JavaScript or TypeScript file, export a function handler. For example, let’s say in your ./functions directory, you have a file, hello.js, containing:
// GET requests to /filename would return "Hello, world!"
export const onRequestGet = () => {
  return new Response("Hello, world!")
}

// POST requests to /filename with a JSON-encoded body would return "Hello, <name>!"
export const onRequestPost = async ({ request }) => {
  const { name } = await request.json()
  return new Response(`Hello, ${name}!`)
}
If you perform a git commit, it will trigger a new Pages build to deploy your dynamic site! During the build pipeline, Pages traverses your directory, mapping the filenames to URLs relative to your repo structure.
Under the hood, Pages generates Workers which include all your routing and functionality from the source. Functions supports deeply-nested routes, wildcard matching, middleware for things like authentication and error-handling, and more! To demonstrate all of its bells and whistles, we’ve created a blog post to walk through an example full stack application.
Letting you do what you do best
As your site grows in complexity, with Pages’ new full stack functionality, your developer experience doesn’t have to. You can enjoy the workflow you know and love while unlocking even more depth to your site.
Seamlessly build
In the same way we’ve handled builds and deployments with your static sites — with a `git commit` and `git push` — we’ll deploy your functions for you automatically. As long as your directory follows the proper structure, Pages will identify and deploy your functions to our network with your site.
Define your bindings
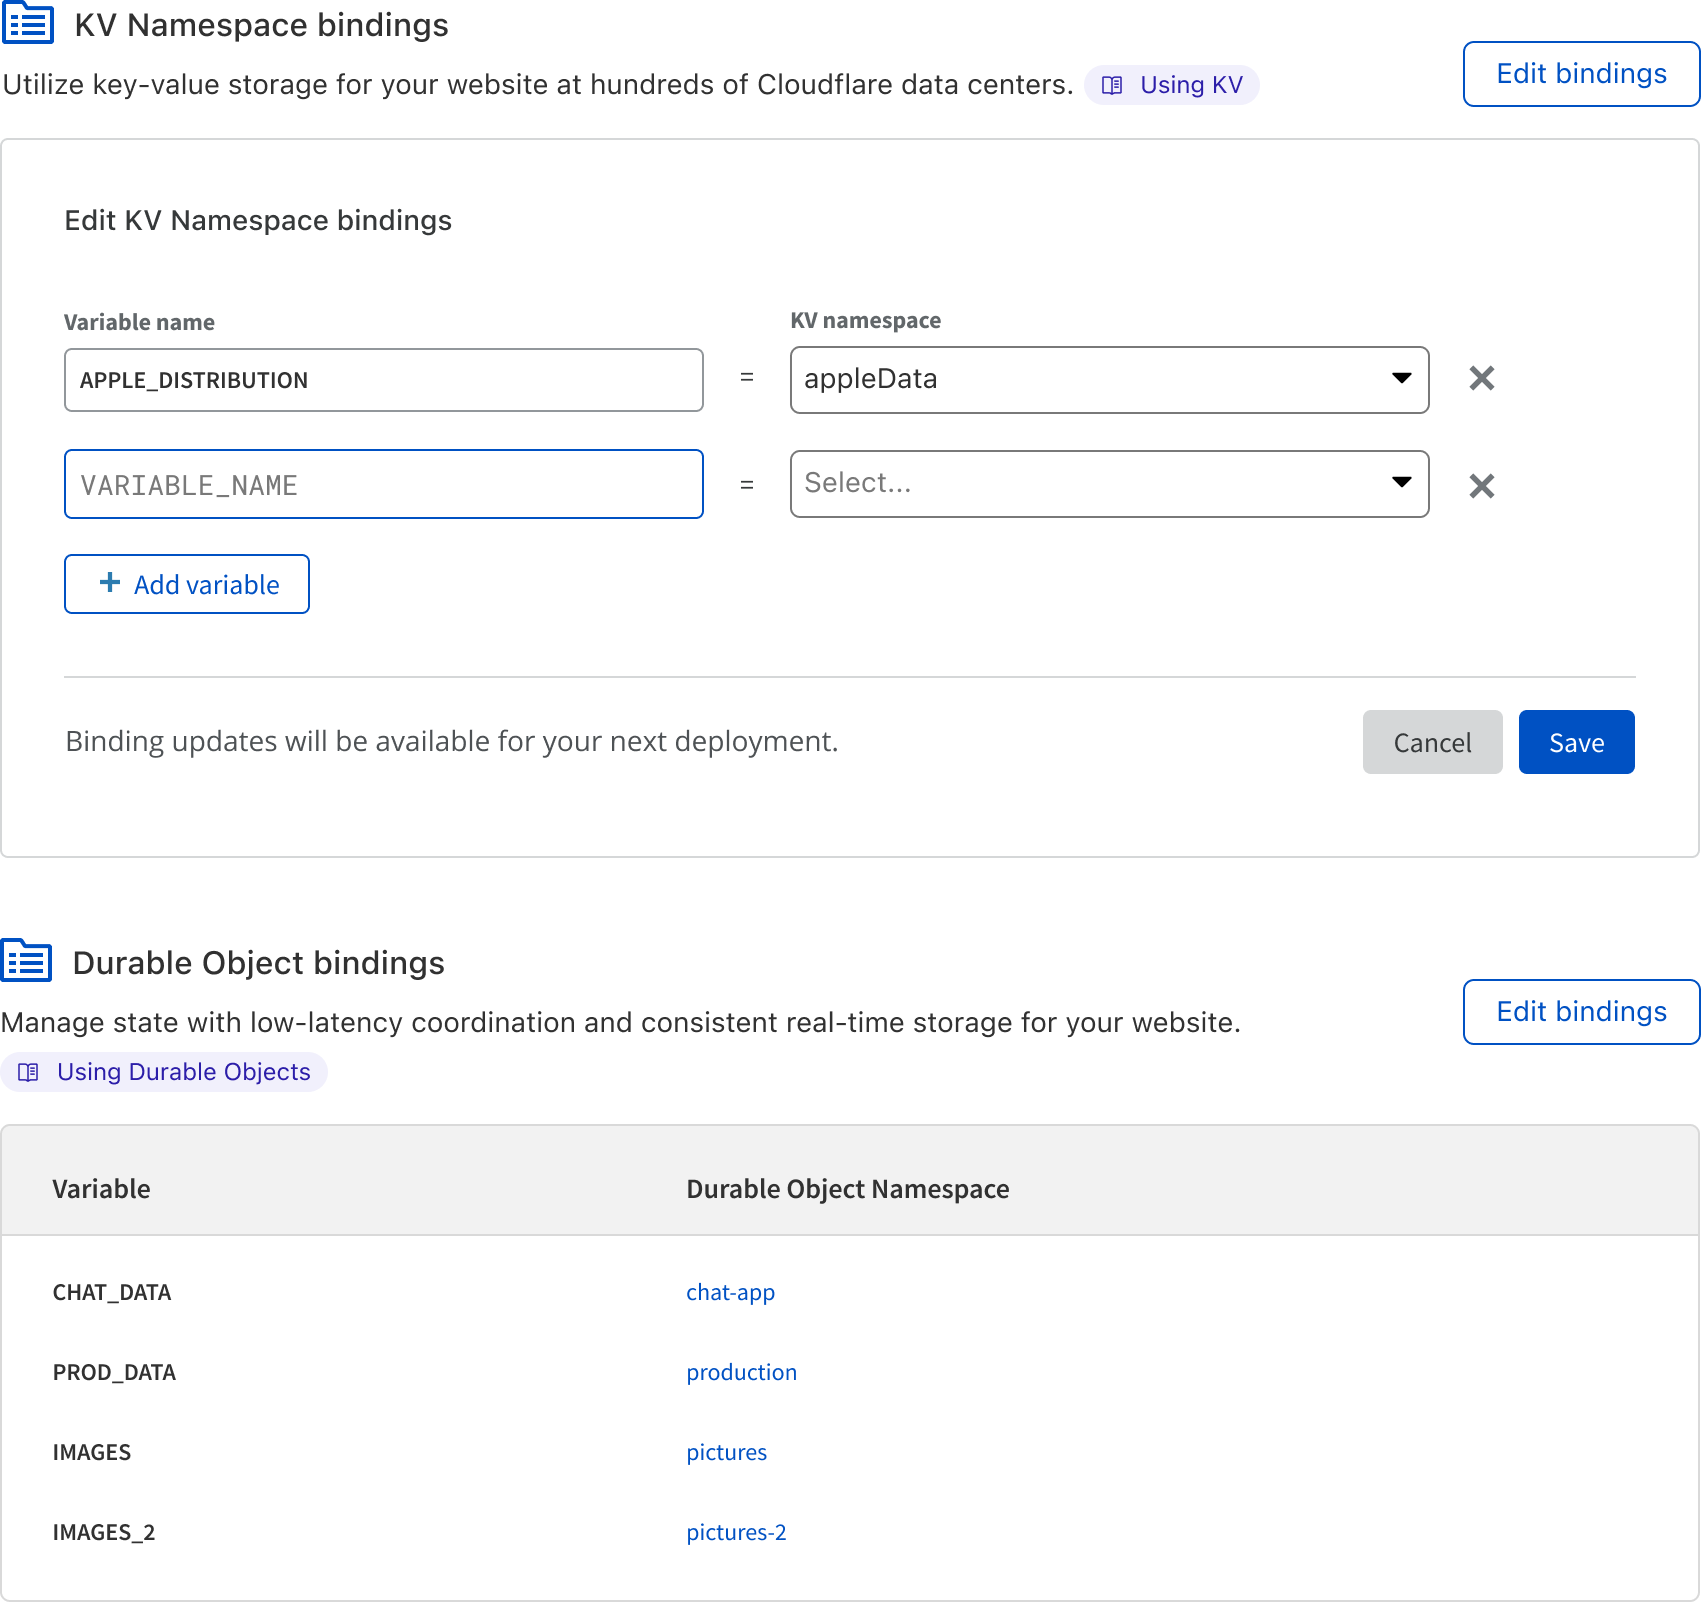
While bringing your Workers to Pages, bindings are a big part of what makes your application a full stack application. We’re so excited to bring to Pages all the bindings you’ve previously used with regular Workers!
KV namespace: Our serverless and globally accessible key-value storage solution. Within Pages, you can integrate with any of the KV namespaces you set in your Workers dashboard for your Pages project.
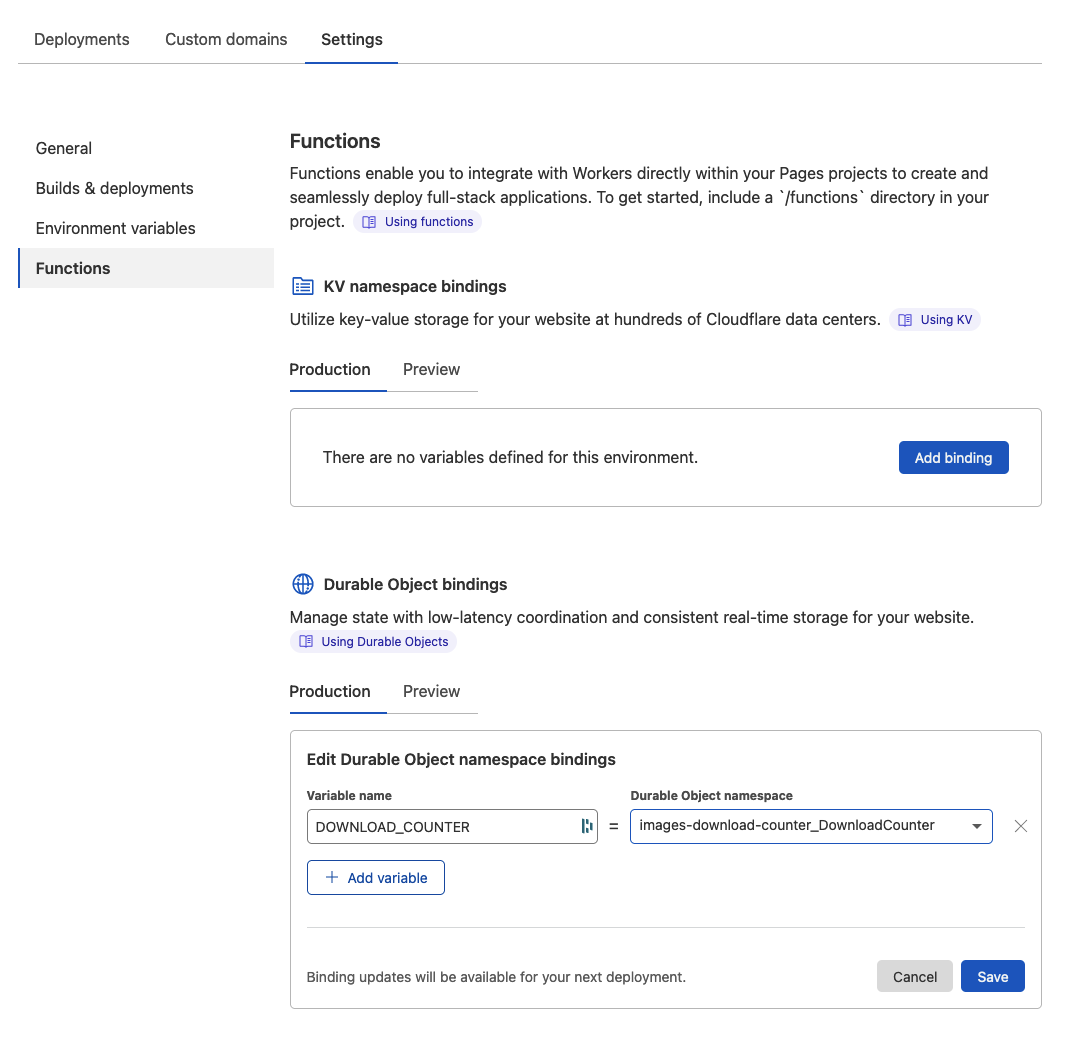
Durable Object namespace: Our strongly consistent coordination primitive that makes connecting WebSockets, handling state and building entire applications a breeze. As with KV, you can set your namespaces within the Workers dashboard and choose from that list within the Pages interface.
Environment Variable: An injected value that can be accessed by your functions and is stored as plain-text. You can set your environment variables directly within the Pages interface for both your production and preview environments at build-time and run-time.
Secret (coming soon!): An encrypted environment variable, which cannot be viewed by wrangler or any dashboard interfaces. Secrets are a great home for sensitive data including passwords and API tokens.
Preview deployments — now for your backend too
With the deployment of your serverless functions, you can still enjoy the ease of collaboration and testing like you did previously. Before you deploy to production, you can easily deploy your project to a preview environment to stage your changes. Even with your functions, Pages lets you keep a version history of every commit with a unique URL for each, making it easy to gather feedback whether it’s from a fellow developer, PM, designer or marketer! You can also enjoy the same infinite staging privileges that you did for static sites, with a consistent URL for the latest changes.
Develop and preview locally too
However, we realize that building and deploying with every small change just to stage your changes can be cumbersome at times if you’re iterating quickly. You can now develop full stack Pages applications with the latest release of our wrangler CLI. Backed by Miniflare, you can run your entire application locally with support for mocked secrets, environment variables, and KV (Durable Objects support coming soon!). Point wrangler at a directory of static assets, or seamlessly connect to your existing tools:
# Install wrangler v2 beta
npm install wrangler@beta

# Serve a folder of static assets
npx wrangler pages dev ./dist

# Or automatically proxy your existing tools
npx wrangler pages dev -- npx react-scripts start
This is just the beginning of Pages’ integrations with wrangler. Stay tuned as we continue to enhance your developer experience.
What else can you do?
Everything you can do with HTTP Workers today!
When deploying a Pages application with functions, Pages is compiling and deploying first class Workers on your behalf. This means there is zero functionality loss when deploying a Worker within your Pages application — instead, there are only new benefits to be gained!
Integrate with SvelteKit — out of the box!
SvelteKit is a web framework for building Svelte applications. It’s built and maintained by the Svelte team, which makes it the Svelte user’s go-to solution for all their application needs. Out of the box, SvelteKit allows users to build projects with complex API backends.
As of today, SvelteKit projects can attach and configure the @sveltejs/adapter-cloudflare package. After doing this, the project can be added to Pages and is ready for its first deployment! With Pages, your SvelteKit project(s) can deploy with API endpoints and full server-side rendering support. Better yet, the entire project — including the API endpoints — can enjoy the benefits of preview deployments, too! This, even on its own, is a huge victory for advanced projects that were previously on the Workers adapter. Check out this example to see the SvelteKit adapter for Pages in action!
Use server-side rendering
You are now able to intercept any request that comes into your Pages project. This means that you can define Workers logic that will receive incoming URLs and, instead of serving static HTML, your Worker can render fresh HTML responses with dynamic data.
For example, an application with a product page can define a single product/[id].js file that will receive the id parameter, retrieve the product information from a Workers KV binding, and then generate an HTML response for that page. Compared to a static-site generator approach, this is more succinct and easier to maintain over time since you do not need to build a static HTML page per product at build-time… which may potentially be tens or even hundreds of thousands of pages!
Already have a Worker? We’ve got you!
If you already have a single Worker and want to bring it right on over to Pages to reap the developer experience benefits of our platform, our announcement today also enables you to do precisely that. Your build can generate an ES module Worker called _worker.js in the output directory of your project, perform your git commands to deploy, and we’ll take care of the rest! This can be especially advantageous to you if you’re a framework author or have a more complex use case that doesn’t follow our provided file structure.
Try it at no cost — for a limited time only
We’re thrilled to be releasing our open beta today for everyone to try at no additional cost to your Cloudflare plan. While we will still have limits in place, we are using this open beta period to learn more about how you and your teams are deploying functions with your Pages projects. For the time being, we encourage you to lean into your creativity and build out that site you’ve been thinking about for a long time — without the worry of getting billed.
In just a few short months, when we announce General Availability, you can expect our billing to reflect that of the Workers Bundled plan — after all, these are just Workers under the hood!
Coming up…
As we’re only announcing this release as an open beta, we have some really exciting things planned for the coming weeks and months. We want to improve on the quick and easy Pages developer experience that you’re already familiar with by adding support for integrated logging and more analytics for your deployed functions.
Beyond that, we’ll be expanding our first-class support for the next generation of frontend frameworks. As we’ve shown with SvelteKit, Pages’ ability to seamlessly deploy both static and dynamic code together enables unbeatable end-user performance & developer ease, and we’re excited to unlock that for more people. Fans of similar frameworks & technologies, such as NextJS, NuxtJS, React Server Components, Remix, Hydrogen, etc., stay tuned to this blog for more announcements. Or better yet, come join us and help make it happen!
Additionally, as we’ve done with SvelteKit, we’re looking to include more first-class integration with existing frameworks, so Pages can become the primary home for your preferred frameworks of choice. Work is underway on making NextJS, NuxtJS, React Server Components, Shopify Hydrogen and more integrate seamlessly as you develop your full stack apps.
Finally, we’re working to speed up those build times, so you can focus on pushing changes and iterating quickly — without the wait!
Getting started
To get started head over to our Pages docs and check out our demo blog to learn more about how to deploy serverless functions to Pages using Cloudflare Workers.
Of course, what we love most is seeing what you build! Pop into our Discord and show us how you’re using Pages to build your full stack apps.
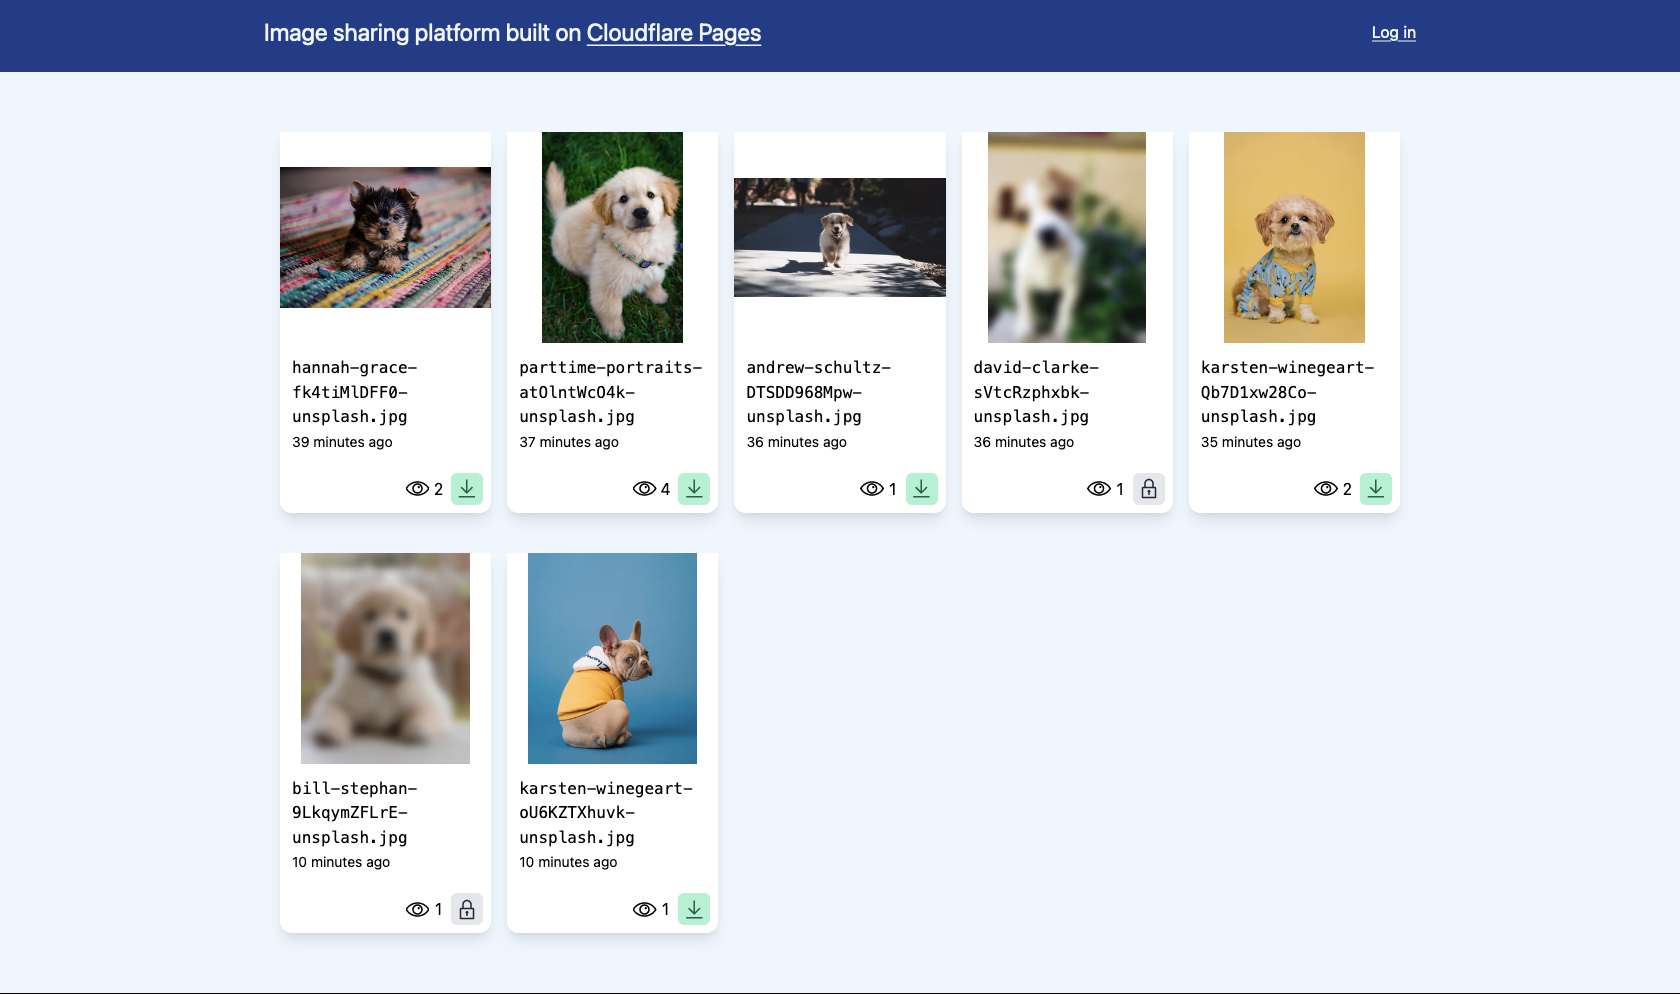
We were so excited to announce support for full stack applications in Cloudflare Pages that we knew we had to show it off in a big way. We’ve built a sample image-sharing platform to demonstrate how you can add serverless functions right from within Pages with help from Cloudflare Workers. With just one new file to your project, you can add dynamic rendering, interact with other APIs, and persist data with KV and Durable Objects. The possibilities for full-stack applications, in combination with Pages’ quick development cycles and unlimited preview environments, gives you the power to create almost any application.
Today, we’re walking through our example image-sharing platform. We want to be able to share pictures with friends while still also keeping some images private. We’ll build a JSON API with Functions (storing data on KV and Durable Objects), integrate with Cloudflare Images and Cloudflare Access, and use React for our front end.
Building serverless functions with Cloudflare Pages
File-based routing
If you’re not already familiar, Cloudflare Pages connects with your git provider (GitHub and GitLab), and automates the deployment of your static site to Cloudflare’s network. Functions lets you enhance these apps by sprinkling in dynamic data. If you haven’t already, you can sign up here.
git commit-ing and pushing this file should trigger a build and deployment of your first Pages function. Any requests for /time will be served by this function, and all other requests will fall-back to the static assets of your project. Placing Functions files in directories works as you’d expect: ./functions/api/time.js would be available at /api/time and ./functions/some_directory/index.js would be available at /some_directory.
We also support TypeScript (./functions/time.ts would work just the same), as well as parameterized files:
./functions/todos/[id].js with single square brackets will match all requests like /todos/123;
and ./functions/todos/[[path]].js with double square brackets, will match requests for any number of path segments (e.g. /todos/123/subtasks).
We declare a PagesFunction type in the @cloudflare/workers-types library which you can use to type-check your Functions.
Dynamic data
So, returning to our image-sharing app, let’s assume we already have some images uploaded, and we want to display them on the homepage. We’ll need an endpoint which will return a list of these images, which the front-end can call:
Eagle-eyed readers will notice we’re exporting onRequestGet which lets us only respond to GET requests.
We’re also using a KV namespace (accessed with env.IMAGES) to store information about images that have been uploaded. To create a binding in your Pages project, navigate to the “Settings” tab.
Interfacing with other APIs
Cloudflare Images is an inexpensive, high-performance, and featureful service for hosting and transforming images. You can create multiple variants to render your images in different ways and control access with signed URLs. We’ll add a function to interface with this service’s API and upload incoming files to Cloudflare Images:
We’re already using KV to store information that is read often but rarely written to. What about features that require a bit more synchronicity?
Let’s add a download counter to each of our images. We can create a highres variant in Cloudflare Images, and increment the counter every time a user requests a link. This requires a bit more setup, but unlocking the power of Durable Objects in your projects is absolutely worth it.
We’ll need to create and publish the Durable Object class capable of maintaining this download count:
// ./durable_objects/downloadCounter.js
ts#example---counter

export class DownloadCounter {
  constructor(state) {
    this.state = state;
    // `blockConcurrencyWhile()` ensures no requests are delivered until initialization completes.
    this.state.blockConcurrencyWhile(async () => {
      let stored = await this.state.storage.get("value");
      this.value = stored || 0;
    });
  }

  async fetch(request) {
    const url = new URL(request.url);
    let currentValue = this.value;

    if (url.pathname === "/increment") {
      currentValue = ++this.value;
      await this.state.storage.put("value", currentValue);
    }

    return jsonResponse(currentValue);
  }
}
Middleware
If you need to execute some code (such as authentication or logging) before you run your function, Pages offers easy-to-use middleware which can be applied at any level in your file-based routing. By creating a _middleware.ts file in a directory, we know to first run this file, and then execute your function when next() is called.
In our application, we want to prevent unauthorized users from uploading images (/api/admin/upload) or deleting images (/api/admin/delete). Cloudflare Access lets us apply role-based access control to all or part of our application, and you only need a single file to integrate it into our serverless functions. We create ./functions/api/admin/_middleware.ts which will apply to all incoming requests at /api/admin/*:
// ./functions/api/admin/_middleware.ts

const validateJWT = async (jwtAssertion: string | null, aud: string) => {
  // If the JWT is valid, return the JWT payload
  // Else, return false
  // https://developers.cloudflare.com/cloudflare-one/identity/users/validating-json

  return jwtPayload;
};

const cloudflareAccessMiddleware: PagesFunction<{ IMAGES: KVNamespace }> =
  async ({ request, env, next, data }) => {
    const { aud } = (await env.IMAGES.get("setup", "json")) as Setup;

    const jwtPayload = await validateJWT(
      request.headers.get("CF-Access-JWT-Assertion"),
      aud
    );

    if (jwtPayload === false)
      return new Response("Access denied.", { status: 403 });

    // We could also use the data object to pass information between middlewares
    data.user = jwtPayload.email;

    return await next();
  };

export const onRequest = [cloudflareAccessMiddleware];
Middleware is a powerful tool at your disposal allowing you to easily protect parts of your application with Cloudflare Access, or quickly integrate with observability and error logging platforms such as Honeycomb and Sentry.
Integrating as Jamstack
The “Jam” of “Jamstack” stands for JavaScript, API and Markup. Cloudflare Pages previously provided the ‘J’ and ‘M’, and with Workers in the middle, you can truly go full-stack Jamstack.
Your front end simply needs to make a call to the Functions we’ve already configured, and render out that data. We’re using SWR to simplify things, but you could do this with entirely vanilla JavaScript fetch-es, if that’s your preference.
// ./src/components/ImageGrid.tsx

export const ImageGrid = () => {
  const { data, error } = useSWR<{ images: Image[] }>("/api/images");

  if (error || data === undefined) {
    return <div>An unexpected error has occurred when fetching the list of images. Please try again.</div>;
  }


  return (
    <div>
      {data.images.map((image) => (
        <ImageCard image={image} key={image.id} />
      ))}
    </div>
  );

}
Local development
No matter how fast it is, iterating on a project like this can be painful if you have to push up every change in order to test how it works. We’ve released a first-class integration with wrangler for local development of Pages projects, including full support for Functions, Workers, secrets, environment variables and KV. Durable Objects support is coming soon.
Install from npm:
npm install wrangler@beta
and either serve a folder of static assets, or proxy your existing tooling:
# Serve a directory
npx wrangler pages dev ./public

# or integrate with your other tools
npx wrangler pages dev -- npx react-scripts start
We are so excited about the future of the Pages platform, and we want to hear what you’re building! Show off your full-stack applications in the #what-i-built channel, or get assistance in the #pages-help channel on our Discord server.
In the early stages of our ideation of Pages, we set out to build a platform with a smooth developer experience that integrates seamlessly with your existing workflow. However, after announcing Pages’ general availability, we realized our platform may not actually be usable by every developer. Before today, only those of you who used GitHub as your source code management tool could take advantage of the Pages experience.
As part of Full Stack Week, we’re opening the doors of our platform to even more users by announcing our integration with GitLab — the DevOps platform! You can now create new Pages projects by connecting your repos stored on GitLab and make site changes there via your usual git commands. And what’s more? We’re also launching an official partnership with GitLab to bring you even better integrations with the git provider in the months to come.
Why GitLab?
As a Jamstack platform, our goal is to enable you, the developer, to focus on what you do best — code, code, code — without the heavy lifting! Not only does this mean giving you all the tools you need to build out a full stack site but also provide you with integrations that fit your development needs. By expanding our platform ecosystem to GitLab, Cloudflare can now serve the needs of a broader developer community collaborating on their sites.
Since our April launch, one of the most common questions and pieces of feedback we’ve received in customer calls, on Discord/Twitter, and on our community threads centered around GitLab. We knew our git integration story couldn’t just stop at one provider, especially given the diversity in tooling we see among our community. So it became glaringly obvious we needed to extend Pages to the GitLab community.
Our partnership
Today, we’re proud to now be official technology partners with GitLab Inc. In addition to our git integration, the goal of our partnership is to improve existing and develop future integrations, so your teams can seamlessly collaborate and accelerate site delivery and updates at scale. As you begin using Pages with GitLab, our teams will be working closely together in a cross-collaborative approach for new integrations.
Developers can be more productive when they create, test, secure and deploy software from a single devops application instead of bouncing between multiple different tools. Cloudflare Pages’ integration with GitLab makes it easier for joint users to develop and deploy new code to Cloudflare’s network using the same syntax and git commands they’re already comfortable using. — Michael LeBeau, Alliance Manager at GitLab
Get started
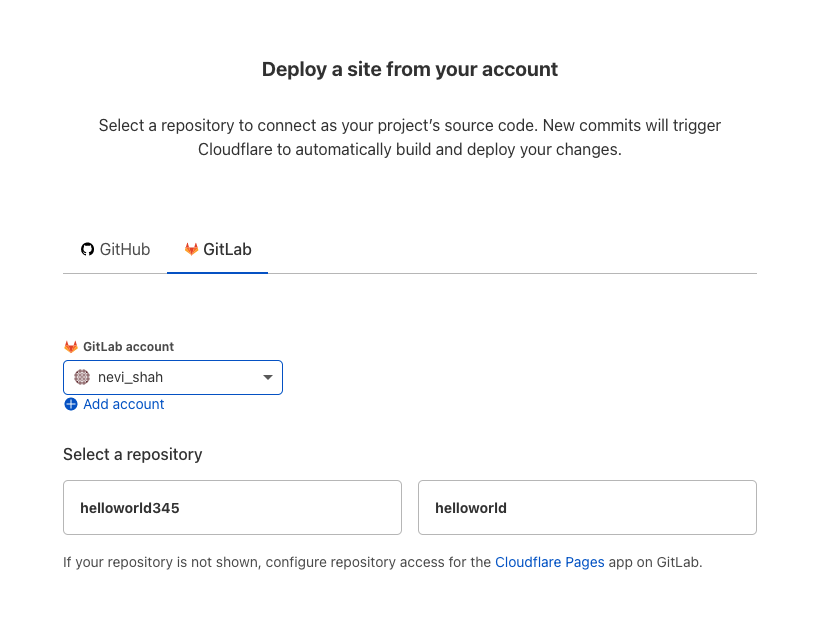
To set up your first project with GitLab, just create a new project in the Pages dashboard. Select “GitLab” and Pages will bring you to your GitLab sign-in screen where you can sign in to your account. Then, select the repo with which you’d like to create your project, configure your build settings, and deploy! From here, you can begin making changes to your site directly via commits to GitLab, triggering a new build every time.
Have questions? To get started, check out the Pages docs and be sure to leave us some feedback by clicking the “Give Feedback” button there. Show us what you build by joining the chatter in our Discord channel.
Much of a developer’s work is about making trade-offs: consistency versus availability, speed over correctness, you name it. While there will always be different technical trade-offs to consider, we believe there are some that you, as a developer, should never need to make.
One of those decisions is an easy-to-use development environment. Whether you’re onboarding a new developer to your team or you simply want to develop faster, it’s important that even the smallest of things are optimized for speed and simplicity.
That’s why we’re excited to announce the second-generation of our developer tooling for Cloudflare Workers. It’s a new developer experience that’s out-of-the-box, lightning fast, and can even run Workers on a local machine. (Yes!)
If you’re already familiar with our existing tools, we’re not just talking about the wrangler CLI, we’re talking about its next major release: wrangler 2.0. Stick around to get a sneak-peak at the new experience.
No config? No problem
We’ve made it much easier to get started with Cloudflare Workers. All you need is a single JavaScript file to run a Worker — no configuration needed. You don’t even need to decide on a name!
When you run wrangler dev <filename>, your code is automatically bundled and deployed to a development environment. Then, you can send HTTP requests to that environment using a localhost proxy. Here’s what that looks like in-action:
Live debugging, just like that
Now there’s a completely redesigned experience for debugging a Worker. With a simple command you get access to a remote debugger, the same used by Chrome when you click “Inspect,” which provides an interactive view of logs, exceptions, and requests. It feels like your Worker is running locally, yet it’s actually running on the Cloudflare network.
A debugger that “just works” and auto-detects your changes makes all the difference when you’re just trying to code. We’ve also made a number of improvements to make the debugging experience even easier:
Keybind shortcuts, to quickly toggle features or open a window.
Support for “–public <path>”, to automatically serve your static assets.
Faster and more reliable file-watching.
To start a debugging session, just run: wrangler dev <filename>, then hit the “D” keybind.
Local mode? Flip a switch
Another aspect of the new debugging experience is the ability to switch to “local mode,” which runs your Worker on your local machine. In fact, you can easily switch between “network” and “local” mode with just a keybind shortcut.
How does this work? Recently, we announced that Miniflare (created by Brendan Coll), a project to locally emulate Workers in Node.js, has joined the Cloudflare organization. Miniflare is great for unit testing and situations where you’d like to debug Workers without an Internet connection. Now we’ve integrated it directly into the local development experience, so you can enjoy the benefits of both the network and your localhost!
Let us know what you think!
Serverless should be simple. We’re really excited about these improvements to the developer experience for Workers, and we have a lot more planned.
While we’re still working on wrangler 2.0, you can try the beta release by running: npm install wrangler@beta or by visiting the repository to see what we’re working on. If you’re already using wrangler to deploy existing applications, we recommend continuing to use wrangler 1.0 until the 2.0 release is officially out. We will continue to develop and maintain wrangler 1.0 until we’re finished with backwards-compatibility for 2.0.
If you’re starting a project or want to try out the new experience, we’d love to hear your feedback! Let us know what we’re missing or what you’d like to see in wrangler 2.0. You can create a feature request or start a discussion in the repository. (we’ll merge them into the existing wrangler repository when 2.0 is out of beta).
Thank you to all of our developers out there, and we look forward to seeing what you build!
Historically, keeping our Rust and TypeScript type repos up to date has been hard. They were manually generated, which means they ran the risk of being inaccurate or out of date. Until recently, the workers-types repository needed to be manually updated whenever the types changed. We also used to add type information for mostly complete browser APIs. This led to confusion when people would try to use browser APIs that aren’t supported by the Workers runtime they would compile but throw errors.
That all changed this summer when Brendan Coll, whilst he was interning with us, built an automated pipeline for generating them. It runs every time we build the Workers runtime, generating types for our TypeScript and Rust repositories. Now everything is up-to-date and accurate.
A quick overview
Every time the Workers runtime code is built, a script runs over the public APIs and generates the Rust and TypeScript types as well as a JSON file containing an intermediate representation of the static types. The types are sent to the appropriate repositories and the JSON file is uploaded as well in case people want to create their own types packages. More on that later.
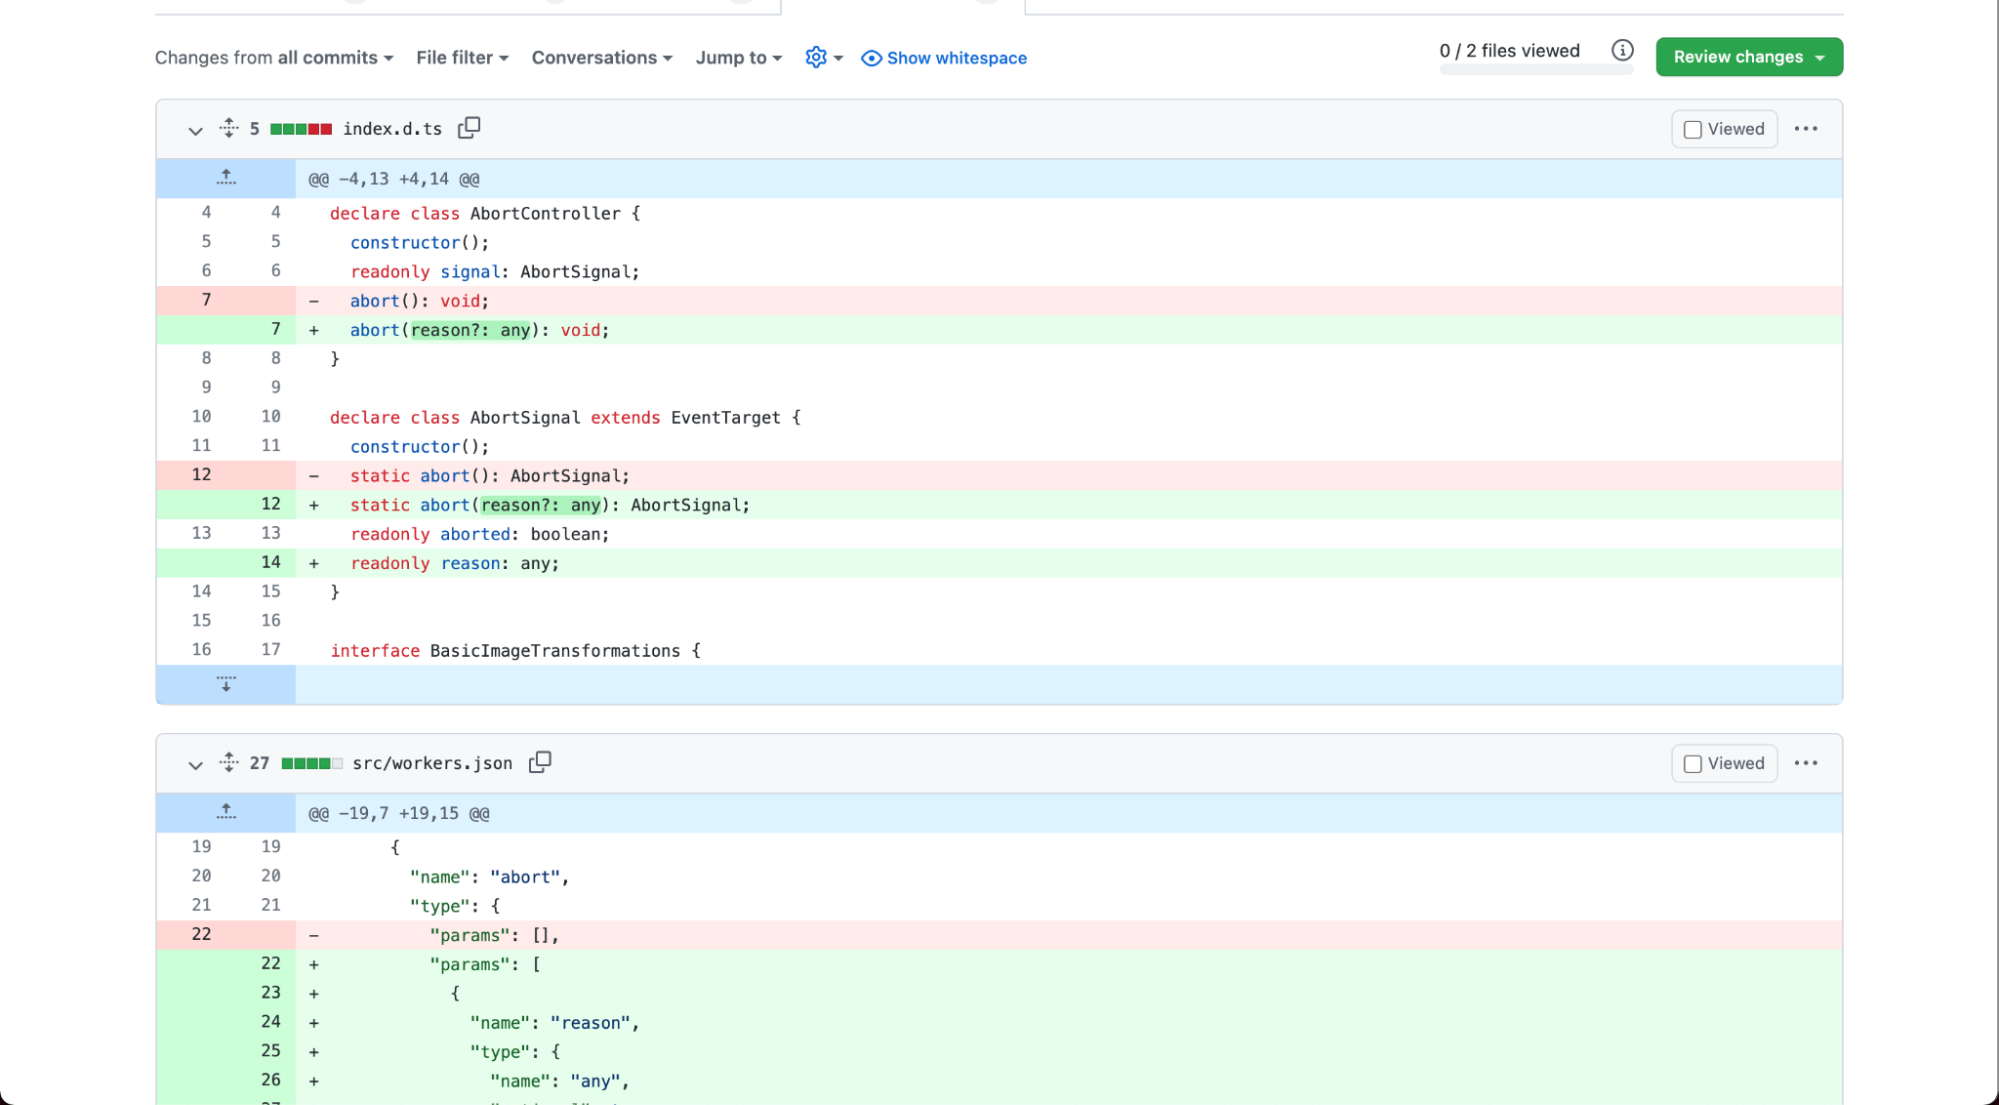
This means the static types will always be accurate and up to date. It also allows projects running Workers in other, statically-typed languages to generate their own types from our intermediate representation. Here is an example PR from our Cloudflare bot. It’s detected a change in the runtime types and is updating the TypeScript files as well as the intermediate representation.
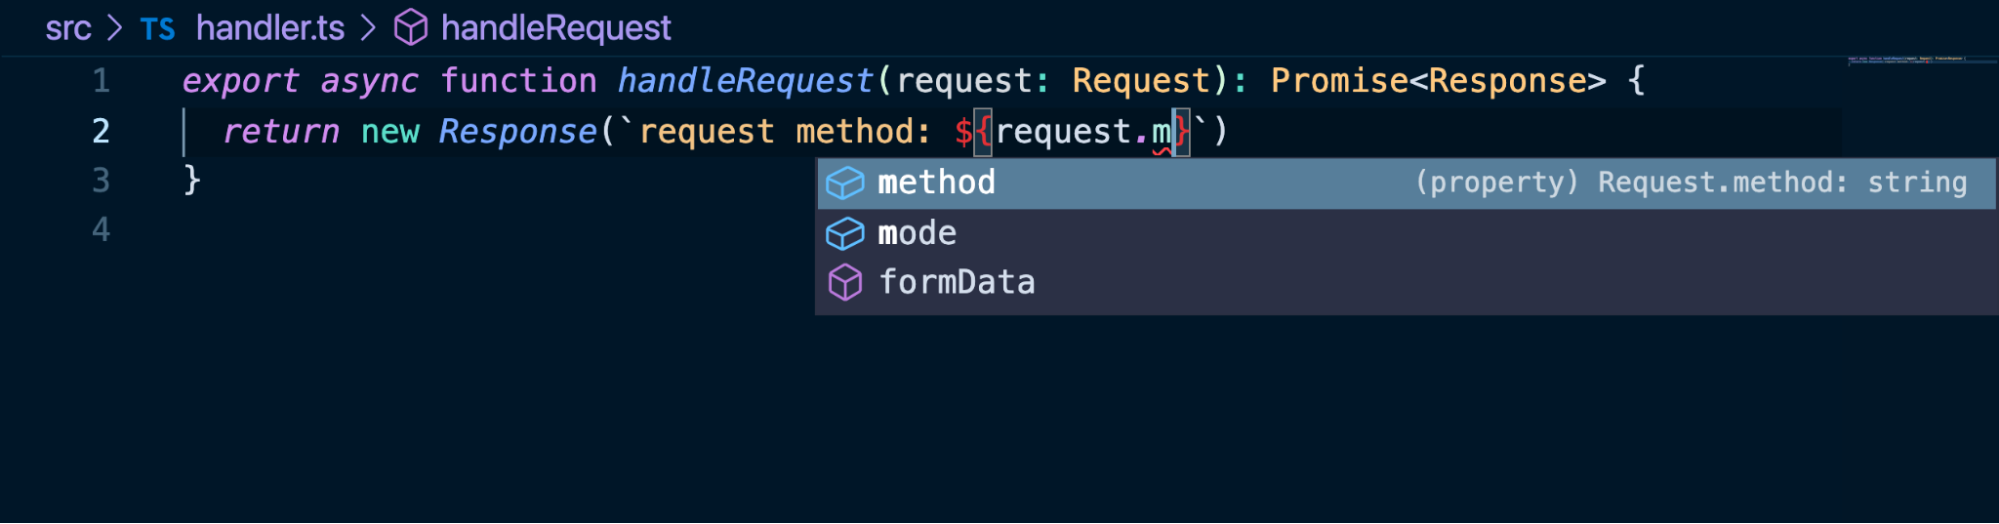
Using the auto-generated types
To get started, use wrangler to generate a new TypeScript project:
A Python script runs over this code during each build and generates an Abstract Syntax Tree containing information about the function including an identifier, any argument types and any return types.
In some cases, TypeScript supports concepts that our C++ runtime does not. Namely, generics and function overloads. In these cases, we override the generated types with partial declarations. For example, DurableObjectStorage makes heavy use of generics for its getter and setter functions.
You can also write type overrides using Markdown. Here is an example of overriding types of KVNamespace.
Creating your own types
The JSON IR (intermediate representation) has been open sourced alongside the TypeScript types and can be found in this GitHub repository. We’ve also open sourced the type schema itself, which describes the format of the IR. If you’re interested in generating Workers types for your own language, you can take the IR, which describes the declaration in a “normalized” data structure, and generate types from it.
The declarations inside `workers.json` contain the elements to derive function signatures and other elements needed for code generation such as identifiers, argument types, return types and error management. A concrete use-case would be to generate external function declarations for a language that compiles to WebAssembly, to import precisely the set of available function calls available from the Workers runtime.
Conclusion
Cloudflare cares deeply about supporting the TypeScript and Rust ecosystems. Brendan created a tool which will ensure the type information for both languages is always up-to-date and accurate. We also are open-sourcing the type information itself in JSON format, so that anyone interested can create type data for any language they’d like!
We’re excited to announce that JavaScript modules are now supported on Cloudflare Workers. If you’ve ever taken look at an example Worker written in JavaScript, you might recognize the following code snippet that has been floating around the Internet the past few years:
The above syntax is known as the “Service Worker” API, and it was proposed to be standardized for use in web browsers. The idea is that you can attach a JavaScript file to a web page to modify its HTTP requests and responses, acting like a virtual endpoint. It was exactly what we needed for Workers, and it even integrated well with standard Web APIs like fetch() and caches.
Before introducing modules, we want to make it clear that we will continue to support the Service Worker API. No developer wants to get an email saying that you need to rewrite your code because an API or feature is being deprecated; and you won’t be getting one from us. If you’re interested in learning why we made this decision, you can read about our commitment to backwards-compatibility for Workers.
What are JavaScript modules?
JavaScript modules, also known as ECMAScript (abbreviated. “ES”) modules, is the standard API for importing and exporting code in JavaScript. It was introduced by the “ES6” language specification for JavaScript, and has been implemented by most Web browsers, Node.js, Deno, and now Cloudflare Workers. Here’s an example to demonstrate how it works:
// filename: ./src/util.js
export function getDate(time) {
  return new Date(time).toISOString().split("T")[0]; // "YYYY-MM-DD"
}
The “export” keyword indicates that the “getDate” function should be exported from the current module. Then, you can use “import” from another module to use that function.
Those are the basics, but there’s a lot more you can do with modules. It allows you to organize, maintain, and re-use your code in an elegant way that just works. While we can’t go over every aspect of modules here, if you’d like to learn more we’d encourage you to read the MDN guide on modules, or a more technical deep-dive by Lin Clark.
How can I use modules in Workers?
You can export a default module, which will represent your Worker. Instead of using “addEventListener,” each event handler is defined as a function on that module. Today, we support “fetch” for HTTP and WebSocket requests and “scheduled” for cron triggers.
You may also notice some other differences, such as the parameters on each event handler. Instead of a single “Event” object, the parameters that you need the most are spread out on their own. The first parameter is specific to the event type: for “fetch” it’s the Request object, and for “scheduled” it’s a controller that contains the cron schedule.
The second parameter is an object that contains your environment variables (also known as “bindings“). Previously, each variable was inserted into the global scope of the Worker. While a simple solution, it was confusing to have variables magically appear in your code. Now, with an environment object, you can control which modules and libraries get access to your environment variables. This mechanism is more secure, as it can prevent a compromised or nosy third-party library from enumerating all your variables or secrets.
The third parameter is a context object, which allows you to register background tasks using waitUntil(). This is useful for tasks like logging or error reporting that should not block the execution of the event.
When you put that all together, you can import and export multiple modules, as well as use the new event handler syntax.
Let’s not forget about Durable Objects, which became generally available earlier this week! You can also export classes, which is how you define a Durable Object class. Here’s another example with a “Counter” Durable Object, that responds with an incrementing value.
// filename: ./src/counter.js
export class Counter {
  value = 0;
  fetch() {
    this.value++;
    return new Response(this.value.toString());
  }
}
// filename: ./src/worker.js
// We need to re-export the Durable Object class in the Worker module.
export { Counter } from "./counter.js"

export default {
  async fetch(request, environment) {
    const clientId = request.headers.get("cf-connecting-ip");
    const counterId = environment.Counter.idFromName(clientId);
    // Each IP address gets its own Counter.
    const counter = environment.Counter.get(counterId);
    return counter.fetch("https://counter.object/increment");
  }
}
Are there non-JavaScript modules?
Yes! While modules are primarily for JavaScript, we also support other modules types, some of which are not yet standardized.
For instance, you can import WebAssembly as a module. Previously, with the Service Worker API, WebAssembly was included as a binding. We think that was a mistake, since WebAssembly should be represented as code and not an external resource. With modules, here’s the new way to import WebAssembly:
import module from "./lib/hello.wasm"

export default {
  async fetch(request) {
    const instance = await WebAssembly.instantiate(module);
    const result = instance.exports.hello();
    return new Response(result);
  }
}
While not supported today, we look forward to a future where WebAssembly and JavaScript modules can be more tightly integrated, as outlined in this proposal. The ergonomics improvement, demonstrated below, can go a long way to make WebAssembly more included in the JavaScript ecosystem.
import { hello } from "./lib/hello.wasm"

export default {
  async fetch(request) {
    return new Response(hello());
  }
}
We’ve also added support for text and binary modules, which allow you to import a String and ArrayBuffer, respectively. While not standardized, it allows you to easily import resources like an HTML file or an image.
import html from "../public/index.html"

export default {
  fetch(request) {
    if (request.url.endsWith("/index.html") {
       return new Response(html, {
          headers: { "Content-Type": "text/html" }
       });
    }
    return fetch(request);
  }
}
How can I get started?
There are many ways to get started with modules.
First, you can try out modules in your browser using our playground (which doesn’t require an account) or by using the dashboard quick editor. Your browser will automatically detect when you’re using modules to allow you to seamlessly switch from the Service Worker API. For now, you’ll only be able to create one JavaScript module in the browser, though supporting multiple modules is something we’ll be improving soon.
If you’re feeling adventurous and want to start a new project using modules, you can try out the beta release of wrangler 2.0, the next-generation of the command-line interface (CLI) for Workers.
For existing projects, we still recommend using wrangler 1.0 (release 1.17 or later). To enable modules, you can adapt your “wrangler.toml” configuration to the following example:
name = "my-worker"
type = "javascript"
workers_dev = true

[build.upload]
format = "modules"
dir = "./src"
main = "./worker.js" # becomes "./src/worker.js"

[[build.upload.rules]]
type = "ESModule"
globs = "**/*.js"

# Uncomment if you have a build script.
# [build]
# command = "npm run build"
We’ve updated our documentation to provide more details about modules, though some examples will still be using the Service Worker API as we transition to showing both formats. (and TypeScript as a bonus!)
If you experience an issue or notice something strange with modules, please let us know, and we’ll take a look. Happy coding, and we’re excited to see what you build with modules!
First, there was the Worker script. It was simple, yet elegant. With just a few lines of code, you could rewrite an HTTP request, append a header, or make a quick fix to your website.
Though, what if you wanted to build an entire application on Workers? You’d need a lot more tools in your developer toolbox. That’s why we’ve introduced extensions to Workers platform like KV, our distributed key-value store; Durable Objects, — a strongly consistent, object-oriented database; and soon R2, the no-egress object storage. While these tools allow you to build a more robust application, there’s still a gap when it comes to building a system architecture, composed of many applications or services.
Imagine you’ve built an authentication service that authorizes requests to your API. You’d want to re-use that logic among all your other services. Moreover, when you make changes to that authentication service, you’d want to test it in a controlled environment that doesn’t affect those other services in production. Well, you don’t need to imagine anymore.
Introducing Services
Services are the new building block for deploying applications on Cloudflare Workers. Unlike the script, a service is composable, which allows services to talk to each other. Services also support multiple environments, which allow you to test changes in a preview environment, then promote to production when you’re confident it worked.
To enable a seamless transition to services, we’ve automatically migrated every script to become a service with one “production” environment — no action needed.
Services have environments
Each service comes with a production environment and the ability to create or clone dozens of preview environments. Every aspect of an environment is overridable: the code, environment variables, and even resources like a KV namespace. You can create and switch between environments with just a few clicks in the dashboard.
Each environment is resolvable at a unique hostname, which is automatically generated when you create or rename the environment. There’s no waiting around after you deploy. Everything you need, like DNS records, SSL certificates, and more, is ready-to-go seconds later. If you’d like a more advanced setup, you can also add custom routes from your domain to an environment.
Once you’ve tested your changes in a preview environment, you’re ready to promote to production. We’ve made it really easy to promote code from one environment to another, without the need to rebuild or upload your code again. Environments also manage code separately from settings, so you don’t need to manually edit environment variables when you promote from staging to production.
Services are versioned
Every change to a service is versioned and audited. Mistakes do happen, but when they do, it’s important to be able to quickly roll back, then have the tools to answer the age-old question: “who changed what, when?”
Each environment in a service has its own version history. Every time there is a code change or an environment variable is updated, the version number of that environment is incremented. You can also append additional metadata to each version, like a git commit or a deployment tag.
Services can talk to each other
Services are composable, allowing one service to talk to another service. To support this, we’re introducing a new API to facilitate service-to-service communication: service bindings.
A service binding allows you to send HTTP requests to another service, without those requests going over the Internet. That means you can invoke other Workers directly from your code! Service bindings open up a new world of composability. In the example below, requests are validated by an authentication service.
Service bindings use the standard fetch API, so you can continue to use your existing utilities and libraries. You can also change the environment of a service binding, so you can test a new version of a service. In the next example, 1% of requests are routed to a “canary” deployment of a service. If a request to the canary fails, it’s sent to the production deployment for another chance.
While the interface among services is HTTP, the networking is not. In fact, there is no networking! Unlike the typical “microservice architecture,” where services communicate over a network and can suffer from latency or interruption, service bindings are a zero-cost abstraction. When you deploy a service, we build a dependency graph of its service bindings, then package all of those services into a single deployment. When one service invokes another, there is no network delay; the request is executed immediately.
This zero-cost model enables teams to share and reuse code within their organizations, without sacrificing latency or performance. Forget the days of convoluted YAML templates or exponential back off to orchestrate services — just write code, and we’ll stitch it all together.
Try out the future, today!
We’re excited to announce that you can start using Services today! If you’ve already used Workers, you’ll notice that each of your scripts have been upgraded to a service with one “production” environment. The dashboard and all the existing Cloudflare APIs will continue to “just work” with services.
You can also create and deploy code to multiple “preview” environments, as part of the open-beta launch. We’re still working on service bindings and versioning, and we’ll provide an update as soon as you can start using them.
For more information about Services, check out any of the resources below:
Go to the dashboard and create your first service!
At Cloudflare, we’re building the best compute platform in the world. We want to make it easy, seamless, and obvious to build your applications with us. But simply making the best compute platform is not enough — at the heart of your applications are the data they interact with.
Cloudflare has multiple data storage solutions available today: Workers KV, R2, and Durable Objects. All three follow Cloudflare’s design goals for Workers: global by default, infinitely scalable, and delightful for developers to use. We’ve partnered with third-party storage solutions like Fauna, MongoDB and Prisma, who have built data platforms that align beautifully with our design goals and written tutorials for databases that already support HTTP connections.
The one area that’s been sorely missed: relational databases. Cloudflare itself runs on relational databases, and we’re not alone. In April, we asked which Node libraries you wanted us to support, and four of the top five requests were related to databases. For this Full Stack Week, we asked ourselves: how could we support relational databases in a way that aligned with our design goals?
Today, we’re taking a first step towards that world by announcing support for relational databases, including Postgres and MySQL from Workers.
Connecting to a database is no simple task — if it were as easy as passing a connection string to a database driver, we would have already done it. We’ve had to overcome several hurdles to reach this point, and have several more still to conquer.
Our goal with this announcement is to work with you, our developers, to solve the unique pain points that come from accessing databases inside Workers. If you’d like to work with us, fill out this form or join us on Discord — this is just the beginning. If you’d just like to grab the code and play around, use this example to get started connecting to your own database, or check out our demo.
Why are Database Connectors so hard to build?
Serverless database connections are challenging to support for several reasons.
Databases are needy — they often require TCP connections, since they assume long-lived connections between an application server and the database. The Workers runtime doesn’t currently support TCP connections, so we’ve only been able to support HTTP-based databases or proxies.
Like a relationship, establishing a connection isn’t quite enough. Developers use client libraries for databases to make submitting queries and managing the responses easy. Since the Workers runtime is not entirely Node.js compatible, we need to either roll our own database library or find one that does not use unsupported built-in libraries.
Finally, databases are sensitive. It often takes external libraries to manage shared connections between an application server and a database, since these connections tend to be expensive to establish.
Moving past these challenges
Our approach today gives us the foundation to address each of these challenges in creative ways going forward.
First, we’re leveraging cloudflared to create a secure tunnel between Cloudflare and a private network within your existing infrastructure. Cloudflared already supports proxying HTTP to TCP over WebSockets — Our challenge is providing interfaces that look like the socket interfaces existing libraries expect, while rewiring the implementations to redirect reads and writes to our websocket. This method is fast, safe, and secure; but limiting in that we lack control of where to direct the final connections. This is a problem we will solve soon, but until then our approach is essential to gathering latency and performance data to see where else we need to improve.
Next, we’ve created a shim-layer that adapts the socket API from a popular runtime to connect directly to databases using a WebSocket. This allows us to bundle code as-is, without forking or otherwise making significant changes to the database library. As part of this announcement, we’ve published a tutorial on how to connect to and query a Postgres database from your Workers, using existing Cloudflare technology and a driver from the growing community at Deno. We’re excited to work with the upstream maintainers, on expanding support.
Finally, we’re most excited for how this approach will let us begin to manage connection pooling and connection establishment overhead. While our current tech demo requires setting up the Cloudflare Tunnel on your own infrastructure, we’re looking for customers who’d like to pilot a model where Cloudflare hosts the tunnel for you.
Where we’re going
We’re just getting started. Our goal with today’s announcement is to find customers who are looking to build new applications or migrate existing applications to Workers while working with data that’s stored in a relational database.
Just as Cloudflare started by providing security, performance, and reliability for customer’s websites, we’re excited about a future where Cloudflare manages database connections, handles replication of data across cloud providers and provides low-latency access to data globally.
First, we’re looking to add support for TCP into the runtime natively. With native support for TCP we’ll not only have better support for databases, but expand the Workers runtime to work with data infrastructure more broadly.
Our position in the network layer of the stack makes providing performance, security benefits and extremely reduced egress costs to global databases all possible realities. To do so, we’ll repurpose the HTTP to TCP proxy service that we’ve currently built and run it for developers as a connection pooling service, managing connections to their databases on their behalf.
Finally, our network makes caching data and making it accessible globally at low latency possible. Once we have connections back to your data, making it globally accessible in Cloudflare’s network will unlock fundamentally new architectures for distributed data.
Take our connectors for a spin
Want to check things out? There are three main steps to getting up-and-running:
Deploying cloudflared within your infrastructure.
Deploying a database that connects to cloudflared.
Deploying a Worker with the database driver that submits queries.
Welcome to a new blog post series called Developer Spotlight. In this series we will be showcasing interesting applications built on top of the Cloudflare Workers Ecosystem.
And to celebrate Durable Objects going GA, what better to kick off the series than with a really cool tech demo of Durable Objects called Full Tilt?
Full Tilt by Guido Zuidhof is a game jam entry for Ludum Dare, one of the biggest and oldest game jams around, where he won first place in the innovation category. A game jam is like a hackathon for games, where you have a very short amount of time (usually 48-72 hours) to create a game from scratch.
We love Full Tilt, not just because Guido used Workers and Durable Objects to build a cool game where you control a game on your computer via your phone, but especially because it shows how powerful Durable Objects are. In less than 48 hours Guido was able to write all the logic to instantly spin up a personal gaming server anywhere in the world, as close to that player as possible. And it is so fast that you feel like you are controlling the computer directly.
But here is Guido, to tell you about his experience developing Full Tilt.
Last October I participated in the Ludum Dare 49 game jam. The thing I love about game jams is that the time constraint forces you to work quickly, iterate often, and most importantly cut scope.
In this game jam I created Full Tilt, a game in which you seamlessly use your phone as a Wiimote-like motion controller for a game that is run on your laptop in a web browser. The secret sauce to making it so smooth was in combining a game jam with Jamstack and mixing in some Durable Objects.
Full Tilt is a browser game in which you move the player character by moving your hand around. There are a few different ways we can do that. One idea would be to use your computer’s webcam to track a marker object through 3D space. While that is possible, it is tricky to get it working in any situation (a dark room can be problematic!) and also some players may feel uncomfortable turning on their webcam for a simple web game.
A smartphone has a bunch of sensors built in, including a magnetometer and gyroscope — those sensors are exactly what we need, and we can assume that the majority of our potential players have a smartphone within arm’s reach. When a native mobile application uses these sensors, it adds a lot of friction (users now have to install an app), as well as a bunch of implementation work. Fortunately modern web browsers allow you to read from these sensors through the DeviceMotion API: a small web app will do the job perfectly!
The next challenge is communicating the sensor readings from the phone to the game running on the main computer. For that we will use a combination of Cloudflare Workers and Durable Objects. There needs to be some shared contact (i.e., a game server) that both the main computer and the smartphone talk to. Using a serverless solution makes a lot of sense for a web game. And as we only have 48 hours here, less stuff to worry about is a big selling point too. Workers and Durable Objects also make it easy to keep the game running after the game jam, without having to pay for — and more importantly worry about — keeping servers running.
Setting up a line of communication
There are roughly two ways for browsers to communicate: through a shared connection (a game server somewhere) or a peer to peer connection, so browsers can talk directly to each other without a middleman by leveraging WebRTC DataChannels.
WebRTC can be very challenging to make reliable and may still need a proxy server for some especially problematic network setups behind multiple NATs. Setting up a WebRTC connection may have been the perfect solution for the lowest possible latency, but it was out of scope for such a short game jam.
The game we are creating has low latency requirements, when I tilt my phone the game should respond quickly. We can probably get away with anything under 100ms, although low double digits or less is definitely preferred! If I’m geographically located in one place and the game server is geographically close enough, then this game server will be able to pass messages from my smartphone to my laptop without too much delay. Edge computing is hot nowadays, and for this gaming use case it is not just a nice-to-have but also a necessity.
Enough background, let’s architect the system.
On-demand game rooms
The first thing I needed to set up was game rooms. Something that both the phone and the computer browsers could connect to, so they can pass messages between them.
Durable Objects allow us to create a large amount of small stateful “mini servers” or “rooms” that multiple clients can connect to simultaneously over WebSockets, providing perfect small on-demand game servers. Think of Durable Objects as a single thread of Javascript that runs in a data center close to where the user first asked for it to be created.
After the browser on the computer starts the game, it asks our Cloudflare Worker API to create a room for the current game session. This API request is a simple POST request, the server responds with a four character room code that uniquely identifies the room that was created. The reason we want the room code to be short is because the user may need to copy this code and type it into their smartphone if they are unable to scan a QR code.
Humans are notoriously bad at copying random character strings as different characters look alike, so we use a limited character set that excludes the most commonly confused characters:
const DICTIONARY = "2345679ADEFGHJKLMNPQRSTUVWXYZ"; // 29 chars (no 0, O, I, 1, B, 8)
A four character code will allow us to uniquely point to ~700,000 different rooms, that seems like it would be enough even if our game got quite popular! What’s more: these game sessions don’t last forever. After some period of time (say 24 hours) we can be certain enough that the game session has ended, and we can re-use that room code.
Room code coordination
In your Cloudflare Worker script, there are two ways to create a Durable Object: either we ask for one to be created with an ID generated from a name, or we ask for one to be created with a random unique ID. The naive solution would be to create a Durable Object with an ID generated from the room code. However, that is not a good idea here because a Durable Object gets created in a data center that is geographically close to the end user.
A problematic situation would be if a user in Mumbai requests a room and gets room code ABCD. Initially, they play the game for a bit, and it works great.
The issue comes a week later when that room code is reused for another player based in Los Angeles, The game room Durable Object will be revived in Mumbai and latency will be awful for our Los Angeles player. In the future, Durable Objects may get migrated between data centers, but that’s not yet guaranteed.
Instead, what we can do is create a new Durable Object with a random ID for every new game session and keep a mapping from the four character room code to this random ID. We are introducing some state in our system: we will need a central source of truth which is where Durable Objects can come to the rescue again.
We will solve this by creating a single “Room Hub” Durable Object that keeps track of this mapping from room code to Durable Object ID. This Durable Object will have two endpoints, one to request a new room and another to look up a room’s information.
Here’s our request handler for the Room Request endpoint (the argument is a Sunder Context, Sunder is the web framework I used for this project):
export async function handleRoomRequest(ctx: Context<Env>) {
const now = Date.now();
const reqBody = await ctx.request.json();
// We make some attempts to find a room that is available..
const attempts = 5
let roomCode: string;
let roomStorageKey: string;
for (let i = 0; i < attempts; i++) {
roomCode = generateRoomCode();
roomStorageKey = ROOM_STATE_PREFIX + roomCode;
const room = await ctx.state.storage.get<RoomData>(roomStorageKey);
if (room === undefined) {
break;
} else if (now - room.createdAt > MAX_ROOM_AGE) {
await ctx.state.storage.delete(roomStorageKey);
break;
}
if (i === attempts-1) {
return ctx.throw("Couldn't find available room code :(");
}
}
const roomData: RoomData = {
roomCode: roomCode,
durableObjectId: reqBody.durableObjectId,
createdAt: now,
}
await ctx.state.storage.put<RoomData>(roomStorageKey, roomData);
ctx.response.body = {
room: roomData
};
ctx.response.status = HttpStatus.Created;
}
In a nutshell, we generate a few room codes until we find one that has never been used or hasn’t been used in a long enough time.
There is a subtle but important nuance in this code: the Durable Object gets created in the Cloudflare Worker that talks to our Room Hub, not in the Room Hub itself. Our Room Hub will run in a single data center somewhere on Cloudflare’s network. If we create the game room from there it may still be far away from our end user!
Looking up a room’s information is simpler, we return either the room data or status 404.
export async function handleRoomLookup(ctx: Context<Env, {roomCode: string}>) {
const now = Date.now();
let roomStorageKey = ROOM_STATE_PREFIX + ctx.params.roomCode;
const roomData = await ctx.state.storage.get<RoomData>(roomStorageKey);
if (roomData === undefined) {
ctx.throw(404, "Room not found");
return;
}
if (now - roomData.createdAt > MAX_ROOM_AGE) {
// About time we cleaned it up.
await ctx.state.storage.delete(roomStorageKey);
ctx.response.status = HttpStatus.NotFound;
return;
}
ctx.response.body = {
room: roomData
};
}
The smartphone browser needs to connect to that same room. To make things easy for the user we generate a four character room code which points at that specific “Game Room” Durable Object. This way the user can take their smartphone, navigate to the website address https://ld49.pages.dev, and enter the code “ABCD” (or more commonly, they scan a QR code with the link https://ld49.pages.dev?room=ABCD).
Game Room Durable Object
Our game room Durable Object can be pretty simple since it is only responsible for passing along messages from the smartphone to the laptop with the latest sensor readings. I was able to modify the Durable Objects chat room example to do exactly this — a good time saver for a game jam!
When a browser connects, they either connect as a “peer” or as a “host” role. Any messages sent by peers are forwarded to the host, and all messages from the host get forwarded to all peers. In this case, our host is the laptop browser running the game and the peer is the smartphone controller. Implementation-wise this means that we keep two lists of users: the peers and the hosts. Whenever a message comes in, we loop over the list to broadcast it to all connections of the other role. In practice, the code is a bit more involved to deal with users disconnecting.
Full Tilt is a singleplayer game, but adapting it to be a multiplayer game would be easy with this setup. Imagine a Mario Kart-like game that runs in your browser in which multiple friends can join using their smartphones as their steering wheel controller! Unfortunately there was not enough time in this game jam to make a polished game.
Front end
With the backend ready, we still need to create the actual game and the controller web app.
My initial plan was to create a game in which you fly a 3D plane by tilting your phone, collecting stars and completing aerobatic tricks. It would fit the theme “Unstable” as I expected this control method to be pretty flimsy! Since there was no time left to create anything close to that, it was time to cut scope.
I ended up using the Phaser game engine and put the entire system together in a Svelte app. This was certainly a challenge, as I had only used Phaser once before many years ago and had never used Svelte. Luckily, I was able to put together something simple quickly enough: a snake-like game in which you move a thingy to collect blips that appear randomly on the screen.
In order for a game to be a game there needs to be some goal for the user, usually some game over condition. I changed the game to go faster and faster over time, added a score counter, and added a game over condition where you lose the game if you touch the edge of the screen. I made my “art” in MS Paint, generated some sound effects using the online tool sfxr, and “composed” the music soundtrack in Chrome’s Music Lab Song Maker.
Simultaneously I wrote a small client for my game server and duct-taped together the smartphone controller app which is powered by the browser’s DeviceMotion APIs. To distribute my game I used Cloudflare Pages, which worked like a charm the first time.
All done
And then the deadline was there — I barely made it, but I submitted something I was proud of. A not-so-great game, but with an interesting backend system and a novel input method. Do try the game yourself here, and the source code is available here (warning: it’s pretty hacky code of course!).
The reception of my co-jammers was great. While everybody agreed the game itself and its graphics were awful, it was novel. The game ended up rated first in the *Innovation* category for this game jam, out of hundreds of other games!
Finally, is this the future of game servers? For indie developers and smaller studios, setting up and maintaining a globally distributed fleet of game servers is both a huge distraction and cost. Serverless and in particular Durable Objects can provide an amazing solution.
But not every game is well-suited for a WebSocket-based backend. In some real-time games you are not interested in what happened a second ago and only the latest information matters. This is where the reliable and ordered nature of WebSockets can get in the way.
All in all my first impressions of Durable Objects are very positive, it is a great tool to have in your toolbelt for all kinds of web projects. You can now tackle problems that would otherwise take days in mere minutes. I am very excited to see what other problems will be made easy by Durable Objects, even those I haven’t even thought of yet.
Today we are excited to announce that we are developing APIs and infrastructure to support more TCP, UDP, and QUIC-based protocols in Cloudflare Workers. Once released, these new capabilities will make it possible to use non-HTTP socket connections to and from a Worker or Durable Object as easily as one can use HTTP and WebSockets today.
Out of the box, fetch and WebSocket APIs. With just a few internal changes to make it operational in Workers, we’ve developed an example using an off-the-shelf driver (in this example, a Deno-based Postgres client driver) to communicate with a remote Postgres server via WebSocket over a secure Cloudflare Tunnel.
import { Client } from './driver/postgres/postgres'

export default {
  async fetch(request: Request, env, ctx: ExecutionContext) {
    try {
      const client = new Client({
        user: 'postgres',
        database: 'postgres',
        hostname: 'https://db.example.com',
        password: '',
        port: 5432,
      })
      await client.connect()
      const result = await client.queryArray('SELECT * FROM users WHERE uuid=1;')
      ctx.waitUntil(client.end())
      return new Response(JSON.stringify(result.rows[0]))
    } catch (e) {
      return new Response((e as Error).message)
    }
  },
}
The example works by replacing the bits of the Postgres client driver that use the Deno-specific TCP socket APIs with standard fetch and WebSockets APIs. We then establish a WebSocket connection with a remote Cloudflare Tunnel daemon running adjacent to the Postgres server, establishing what is effectively TCP-over-WebSockets.
While the fact we were able to build the example and communicate effectively and efficiently with the Postgres server — without making any changes to the Cloudflare Workers runtime — is impressive, there are limitations to the approach. For one, the solution requires additional infrastructure to establish and maintain the WebSocket tunnel — in this case, the instance of the Cloudflare Tunnel daemon running adjacent to the Postgres server. While we are certainly happy to provide that daemon to customers, it would just be better if that component were not required at all. Second, tunneling TCP over WebSockets, which is itself tunneled via HTTP over TCP is a bit suboptimal. It works, but we can do better.
Making connections from Cloudflare Workers
Currently, there is no standard API for socket connections in JavaScript. We want to change that.
If you’ve used Node.js before, then you’re most likely familiar with the net.Socket and net.TLSSocket objects. If you use Deno, then you might know that they’ve recently introduced the Deno.connect() and Deno.connectTLS() APIs. When you look at those APIs, what should immediately be apparent is how different they are from one another despite doing the exact same thing.
When we decided that we would add the ability to open and use socket connections from within Workers, we also agreed that we really have no interest in developing yet another non-standard, platform-specific API that is unlike the APIs provided by other platforms. Therefore, we are extending an invitation to all JavaScript runtime platforms that need socket capabilities to collaborate on a new (and eventually standardized) API that just works no matter which runtime you choose to develop on.
Here’s a rough example of what we have in mind for opening and reading from a simple TCP client connection:
const socket = new Socket({
  remote: { address: '123.123.123.123', port: 1234 },
})
for await (const chunk of socket.readable)
  console.log(chunk)
Or, this example, sending a simple “hello world” packet using UDP:
The API will be designed generically enough to work both client and server-side; for TCP, UDP, and QUIC; with or without TLS, and will not rely on any mechanism specific to any single JavaScript runtime. It will build on existing broadly supported Web Platform standards such as EventTarget, ReadableStream, WritableStream, AbortSignal, and promises. It will be familiar to developers who are already familiar with the fetch() API, service workers, and promises using async/await.
This is just a proposal at this point and the details will very likely change from the examples above by the time the capability is delivered in Workers. It is our hope that other platforms will join us in the effort of developing and supporting this new API so that developers have a consistent foundation upon which to build regardless of where they run their code.
Introducing Socket Workers
The ability to open socket client connections is only half of the story.
When we first started talking about adding these capabilities an obvious question was asked: What about using non-HTTP protocols to connect to Workers? What if instead of just having the ability to connect a Worker to some other back-end database, we could implement the entire database itself on the edge, inside Workers, and have non-HTTP clients connect to it? For that matter, what if we could implement an SMTP server in Workers? Or an MQTT message queue? Or a full VoIP platform? Or implement packet filters, transformations, inspectors, or protocol transcoders?
Workers are far too powerful to limit to just HTTP and WebSockets, so we will soon introduce Socket Workers — that is, Workers that can be connected to directly using raw TCP, UDP, or QUIC protocols without using HTTP.
What will this new Workers feature look like? Many of the details are still being worked through, but the idea is to deploy a Worker script that understands and responds to “connect” events in much the same way that “fetch” events work today. Importantly, this would build on the same common socket API being developed for client connections:
The new socket API for JavaScript and Socket Workers are under active development, with focus initially on enabling better and more efficient ways for Workers to connect to databases on the backend — you can sign up here to join the waitlist for access to Database Connectors and Socket Workers. We are excited to work with early users, as well as our technology partners to develop, refine, and test these new capabilities.
Once released, we expect Socket Workers to blow the doors wide open on the types of intelligent distributed applications that can be deployed to the Cloudflare network edge, and we are excited to see what you build with them.
We’ve heard a common theme over the past year: developers want to build more of their applications on Workers. With built-in global deployments, insane scalability and the flexibility of JavaScript, more and more applications are choosing to build on our global platform.
To do so, developers need access to data. Our strategy for data on Workers has had three parts:
One, to provide first-party solutions that are designed for infinite scale, like Workers KV and Durable Objects.
Two, to support a wide array of NoSQL databases that connect over HTTP, and to begin to build connections to data where it already lives today with TCP Database Connectors.
Three, to partner with best-of-breed data companies to bring their capabilities to the Workers platform.
Today we’re excited to announce that, in addition to our existing partners Fauna and Macrometa, Cloudflare Workers has added support for Prisma and MongoDB Atlas. These data platforms are heavily demanded by developers — Prisma’s modern ORM brings support for Postgres, SQL Server, MySQL via their Prisma client, while MongoDB topped the ranks of integrations most demanded by our users.
Both clients are available in their respective mainline git repositories, realm-web for MongoDB and prisma for Prisma. You can begin using them right away by importing them into your Workers.
What’s great about MongoDB?
MongoDB is a database loved by developers — its document model makes it easy to start with, while transactions and a scale-out distributed systems architecture let it scale with your application.
MongoDB brings a robust query language, MQL, to developers on the Workers platform, supporting rich aggregations right within the database. MongoDB support is provided via the Realm SDK, which integrates directly with MongoDB Atlas — the easiest way to run MongoDB.
MongoDB Atlas also includes Global Cluster, perfect for creating a low-latency, geo-distributed MongoDB database to back your Workers.
Together with MongoDB, we’ve put together a demo application that you can play with on MongoDB’s blog. Check it out and let us know if you have questions!
What’s great about Prisma?
Prisma is an ORM, or object-relational mapper, which transforms entries in a database into objects in code. What makes Prisma great is its ability to abstract away the complexities of working with the database — Prisma handles type-safety, schema migrations, query optimization and the actual interactions between your code and the database. Like Workers does for compute at the edge, Prisma makes managing your database dead-simple.
Prisma currently supports Postgres, MySQL, SQL Server, SQLite and MongoDB. These databases can be existing on any cloud provider or can be spun up on-demand on Heroku.
Prisma integrates with Workers via the Prisma Data Proxy. After setting up the Proxy, you can import the Prisma client into your Workers script and define a schema to begin using any of the supported databases!
What’s next?
Alongside our existing partnerships with Macrometa and Fauna, we’re excited to add the MongoDB and Prisma integrations to Worker’s growing library. If you have a data platform you’d like to use with Workers, reach out to us, and we’ll make it happen!
“Which came first, the chicken or the egg?” It’s one of life’s great questions. There are hundreds of articles published which conclude with eggs predating chickens by millions of years. Unfortunately, Cloudflare users don’t have New Scientist on hand to answer similar questions.
Which runs first, Firewall Rules or Workers? Page Rules or Transform Rules? Whilst not as philosophically challenging, the answers to these questions are key to setting up your Cloudflare zone correctly. Answering them has become increasingly difficult as more and more functionality is added, thanks to our incredible rate of shipping products. What was once a relatively easy to understand traffic flow exploded in complexity with the introduction of products such as Workers, Load Balancing Rules and Transform Rules. And this big bang of product announcements is only accelerating each year.
To begin addressing this problem, we developed Traffic Sequence. Traffic Sequence is a simple dashboard illustration which shows a default, high-level overview of how Cloudflare products interact. Think of this as your atlas, rather than your black cab driver’s “Knowledge”. This helps you understand that London is in the south east of the UK, but not that it’s quicker to walk than use the London Underground between Leicester Square and Covent Garden.
Traffic Sequence is now enabled for all zones by default, appearing on ten product pages within the dashboard. Traffic Sequence highlights in blue the product area you are currently configuring, showing where within the HTTP request lifecycle the specific product sits. This provides context and allows users to understand which products will see the impact of changes here, and which products will not.
Traffic Sequence is designed to make Cloudflare’s edge clearer to our customers, allowing users to understand how products fit together and understand how HTTP requests flow between each.
Dear Cloudflare, which runs first?
Understanding how traffic is routed through Cloudflare has been one of the most common questions from both Cloudflare staff and customers alike.
Love Cloudflare, but still can’t my head around workers. do they come before the cache? After? Page Rules? I’ve asked in the forums and chat , but a single reference doc would be so goood! (specific page rules & cache settings ex: interaction with Cache Everything)
But why does it matter? Let’s go through a simple example.
Released in April 2021, “Transform Rules” lets users rewrite URLs of HTTP requests as they proxy through their zone — for example, rewriting /login.php to /super/secret/login-page.php, all invisible to the end user.
In this scenario, the administrator also has a Firewall Rule blocking requests to the URI Path /login.php when the visitor is coming from a country other than the United States. What they would see, however, is that visitors from these other countries are still reaching the /login.php page on their servers. Why is this?
This is because URL rewrites happen before Firewall Rules, meaning the Firewall Rules product won’t see a URI Path of /login.php. Instead it will see HTTP requests with the rewritten URI path of /super/secret/login-page.php. Thus, when Firewall Rules evaluates the customers rule it checks:
Is this from a country that is not the USA? Yes
AND – Is this request going to a URI Path of /login.php? No.
As both criteria are not evaluated as ‘true’, the rule does not match and the traffic is allowed on its journey.
This is why it is so important to know how Cloudflare’s products interoperate to get the most out of your plan, and achieve your goals without having to dig through mountains of documentation.
In an alternate timeline, Traffic Sequence is used to highlight that Firewall Rules run after URL rewriting occurs, and therefore see’s the rewritten value in the URI Path. With this information the customer can then configure a Firewall Rule to look for the rewritten value in URI Path and accomplish their desired setup.
From napkin to working prototype
Traffic Sequence was originally borne out of a “back of the napkin” idea during the creation of Transform Rules and URL Normalization, in an attempt to show where these transformations were happening:
The idea might have started from a need of our own, but it ended up addressing well known customer and internal problems: whenever we build a new product everyone wants to understand how it fits into the big picture. So we pushed the idea further, proposing it to other teams and soliciting feedback.
This project was a great example of how bringing the right level of fidelity of thinking to the table can be evolved into an opportunity to ship to learn. Something that was initially meant as an explainer diagram for one rule type has become an almost bespoke experience of the dashboard, as it is unique to each customer’s Cloudflare environment, displaying only the products available for use in that zone. We offer many options and routes to products, but we didn’t have a straightforward flow of information that customers can rely on, focusing only on what they have set up and have access to.
As part of the design process, we try to focus on asking lots of questions rather than just finding an answer. Some of the considerations we had were:
What if we show customers a product they aren’t using?
What if we show customers a product they aren’t entitled to on their plan level?
Why aren’t we showing “this product”?
Do we have this visualisation on by default?
After gaining internal momentum to flesh out this project, we decided to focus on three areas:
Simplifying a complex ecosystem – what is a useful simplification?
Value that this will add beyond this first application
Opportunity to test out different navigation and mental models.
After all, this is not just a map of our system, but a new way of navigating it entirely.
Positive early internal feedback not only aligned with our goals, but allowed us to iterate on points that needed improvement. We knew that this could be a game-changer for promoting clarity, improving discoverability and saving time with navigation: going for one click instead of three for most items.
A couple of iterations later, we were ready to put this in the hands of our users for early testing:
Ever wondered how traffic is handled by our various products when configuring your @Cloudflare zone? You arent alone. We hear you. If you are interested in trying our latest experiment, get in touch. We’d LOVE your feedback. #Cloudflarepic.twitter.com/mh906T0JxV
Thanks to our incredible community we had a high level of interest in the first week, providing insight into how this feature would be used in the real world, and answering the ultimate question of this experiment: “Does this solve the problem of understanding how Cloudflare handles HTTP requests?” via our Traffic Sequence survey form:
“I didn’t know where my requests were going… until now.”
“It’s always been confusing which products/features affect which other products/features.”
“It’s really handy to be able to explain the ordering that these are happening in, and I like the deeplink into the relevant area.”
These were all a great reminder that what triggered this work was ingrained in real customer needs.
Other feedback was rapidly incorporated into the prototype; specifically splitting Transform Rules into two separate sections to highlight that URL rewrites and header modifications occur at different parts of the request flow. We also added features which our users deemed important for clarity, such as IP Access Rules.
Traffic Sequence for all
Thanks to the great feedback and participation of all testers, both internal and external, we are now in a position where we are comfortable to take the covers off and make Traffic Sequence available to all users.
The visualisation can be hidden easily by clicking on the “hide” button, and the display automatically hides to preserve critical whitespace when needed:
When new products are added, or updates to products occur which modify the traffic order, this diagram will be updated accordingly.
Evolving Traffic Sequence
We know this is a high level, generic overview of how Cloudflare products interact. There is a level of nuance underneath, and a number of products and features not shown in the Traffic Sequence illustration which play an important part in keeping users safe and secure.
In the future we have aspirations to build “the other side of the coin”. Traffic Sequence provides a simple to understand view of how the products work by default at a high level. We also want to create a detailed, almost traceroute-like feature which allows users to see exactly what happens to their traffic — which products it goes via and what happens within those products, and potentially a lot more. Stay tuned!
Try it now
This feature is now enabled by default on all customer zones, and is visible within the dashboard locations outlined above.
Please do try it out and let us know what you think via the Cloudflare Community
Cloudflare Workers is our serverless platform that runs your code in 250+ cities worldwide.
On the Workers team, we have a policy:
A change to the Workers Runtime must never break an application that is live in production.
It seems obvious enough, but this policy has deep consequences. What if our API has a bug, and some deployed Workers accidentally depend on that bug? Then, seemingly, we can’t fix the bug! That sounds… bad?
This post will dig deeper into our policy, explaining why Workers is different from traditional server stacks in this respect, and how we’re now making backwards-incompatible changes possible by introducing “compatibility dates”.
TL;DR: Developers may now opt into backwards-incompatible fixes by setting a compatibility date.
Serverless demands strict compatibility
Workers is a serverless platform, which means we maintain the server stack for you. You do not have to manage the runtime version, you only manage your own code. This means that when we update the Workers Runtime, we update it for everyone. We do this at least once a week, sometimes more.
This means that if a runtime upgrade breaks someone’s application, it’s really bad. The developer didn’t make any change, so won’t be watching for problems. They may be asleep, or on vacation. If we want people to trust serverless, we can’t let this happen.
This is very different from traditional server platforms, where the developer maintains their own stack. For example, when a developer maintains a traditional VM-based server running Node.js applications, then the developer must decide exactly when to upgrade to a new version of Node.js. Careful developers do not upgrade Node.js 14 to Node.js 16 in production without testing first. They typically verify that their application works in a staging environment before going to production. A developer who doesn’t have time to spend testing each new version may instead choose to rely on a long-term support release, applying only low-risk security patches.
In the old world, if the Node.js maintainers decide to make a breaking change to an obscure API between releases, it’s OK. Downstream developers are expected to test their code before upgrading, and address any breakages. But in the serverless world, it’s not OK: developers have no control over when upgrades happen, therefore upgrades must never break anything.
But sometimes we need to fix things
Sometimes, we get things wrong, and we need to fix them. But sometimes, the fix would break people.
For example, in Workers, the fetch() function is used to make outgoing HTTP requests. Unfortunately, due to an oversight, our original implementation of fetch(), when given a non-HTTP URL, would silently interpret it as HTTP instead. For example, if you did fetch(“ftp://example.com”), you’d get the same result as fetch(“http://example.com”).
This is obviously not what we want and could lead to confusion or deeper bugs. Instead, fetch() should throw an exception in these cases. However, we couldn’t simply fix the problem, because a surprising number of live Workers depended on the behavior. For whatever reason, some Workers fetch FTP URLs and expect to get a result back. Perhaps they are fetching from sites that support both FTP and HTTP, and they arbitrarily chose FTP and it worked. Perhaps the fetches aren’t actually working, but changing a 404 error result into an exception would break things worse. When you have tens of thousands of new developers deploying applications every month, inevitably there’s always someone relying on any bug. We can’t “fix” the bug because it would break these applications.
The obvious solutions don’t work
Could we contact developers and ask them to fix their code?
No, because the problem is our fault, not the application developer’s, and the developer may not have time to help us fix our problems.
The fact that a Worker is doing something “wrong” — like using an FTP URL when they should be using HTTP — doesn’t necessarily mean the developer did anything wrong. Everyone writes code with bugs. Good developers rely on careful testing to make sure their code does what it is supposed to.
But what if the test only worked because of a bug in the underlying platform that caused it to do the right thing by accident? Well, that’s the platform’s fault. The developer did everything they could: they tested their code thoroughly, and it worked.
Developers are busy people. Nobody likes hearing that they need to drop whatever they are doing to fix a problem in code that they thought worked — especially code that has been working fine for years without anyone touching it. We think developers have enough on their plates already, we shouldn’t be adding more work.
Could we run multiple versions of the Workers Runtime?
No, for three reasons.
First, in order for edge computing to be effective, we need to be able to host a very large number of applications in each instance of the Workers Runtime. This is what allows us to run your code in hundreds of locations around the world at minimal cost. If we ran a separate copy of the runtime for each application, we’d need to charge a lot more, or deploy your code to far fewer locations. So, realistically it is infeasible for us to have different Workers asking for different versions of the runtime.
Second, part of the promise of serverless is that developers shouldn’t have to worry about updating their stack. If we start letting people pin old versions, then we have to start telling people how long they are allowed to do so, alerting people about security updates, giving people documentation that differentiates versions, and so on. We don’t want developers to have to think about any of that.
Third, this doesn’t actually solve the real problem anyway. We can easily implement multiple behaviors within the same runtime binary. But how do we know which behavior to use for any particular Worker?
Introducing Compatibility Dates
Going forward, every Worker is assigned a “compatibility date”, which must be a date in the past. The date is specified inside the project’s metadata (for Wrangler projects, in wrangler.toml). This metadata is passed to the Cloudflare API along with the application code whenever it is updated and deployed. A compatibility date typically starts out as the date when the Worker was first created, but can be updated from time to time.
# wrangler.toml
compatibility_date = "2021-09-20"
We can now introduce breaking changes. When we do, the Workers Runtime must implement both the old and the new behavior, and chooses behavior based on the compatibility date. Each time we introduce a new change, we choose a date in the future when that change will become the default. Workers with a later compatibility date will see the change; Workers with an older compatibility date will retain the old behavior.
A page in our documentation lists the history of breaking changes — and only breaking changes. When you wish to update your Worker’s compatibility date, you can refer to this page to quickly determine what might be affected, so that you can test for problems.
We will reserve the compatibility system strictly for changes which cannot be made without causing a breakage. We don’t want to force people to update their compatibility date to get regular updates, including new features, non-breaking bug fixes, and so on.
If you’d prefer never to update your compatibility date, that’s OK! Old compatibility dates are intended to be supported forever. However, if you are frequently updating your code, you should update your compatibility date along with it.
Acknowledgement
While the details are a bit different, we were inspired by Stripe’s API versioning, as well as the absolute promise of backwards compatibility maintained by both the Linux kernel system call API and the Web Platform implemented by browsers.
Last year, I wrote about the Cloudflare Workers security model, including how we fight Spectre attacks. In that post, I explained that there is no known complete defense against Spectre — regardless of whether you’re using isolates, processes, containers, or virtual machines to isolate tenants. What we do have, though, is a huge number of tools to increase the cost of a Spectre attack, to the point where it becomes infeasible. Cloudflare Workers has been designed from the very beginning with protection against side channel attacks in mind, and because of this we have been able to incorporate many defenses that other platforms — such as virtual machines and web browsers — cannot. However, the performance and scalability requirements of edge compute make it infeasible to run every Worker in its own private process, so we cannot rely on the usual defenses provided by the operating system kernel and address space separation.
Given our different approach, we cannot simply rely on others to tell us if we are safe. We had to do our own research. To do this we partnered with researchers at Graz Technical University (TU Graz) to study the impact of Spectre on our environment. The team at TU Graz are some of the foremost experts on the topic, having co-discovered Spectre initially as well as discovered several follow-on bugs like NetSpectre, ZombieLoad, Fallout, and others.
Today we are publishing a paper describing our findings, authored by Martin Schwarzl, Pietro Borrello, Andreas Kogler, Thomas Schuster, Daniel Gruss, Michael Schwarz, and myself. This paper covers research done in 2019 and early 2020. The research both tests the possibility of attacking Workers using Spectre, and proposes a new defense mechanism, which we now employ in production.
For this research, the team at TU Graz had full access to the Workers Runtime source code and were able to compile and run it locally for testing.
The research has two basic components.
Part 1: Develop an attack
A side channel attack (of which Spectre is one variety) is kind of like playing poker with a CPU. In poker, players try to understand what their opponents are thinking by looking for subtle unconscious behaviors, such as a nervous look or a hand motion. These behaviors are called “tells”. In a side channel attack, the attacker wants to find out secrets that the CPU knows. The CPU won’t reveal these secrets directly, but they can sometimes subtly affect how long the CPU spends to perform certain operations, kind of like a poker tell. If an attacker can carefully time the CPU’s actions, they can potentially discover the underlying secrets. Spectre attacks in particular focus on side channels that result from the CPU’s use of speculative execution, in which the CPU executes code that it is not yet sure should be executed, and then attempts to roll it back if not. Speculative execution is a particularly potent tool in side channel attacks because it essentially allows the attacker to program custom side channels in speculatively-executed code.
Many Spectre defenses focus on eliminating the “tells” by trying to prevent the variability in the CPU’s timing. This is hard, because CPUs are extremely complex and there are many ways that their timing can be affected. While many specific “tells” have been found and mitigated, there are undoubtedly many more that haven’t been disclosed. This has led to a game of whack-a-mole, where researchers continuously find new “tells” while CPU vendors rush out kernel and microcode patches to solve them — often with large performance losses as a side effect.
In Workers, we have focused on a different approach: preventing the attacker from seeing the “tells”. The Workers Runtime is designed to prevent a Worker from measuring its own execution time, as well as to prevent other forms of non-deterministic behavior like multithreading that could be used in place of a timer. I described these techniques in detail in last year’s post.
However, this approach can’t be perfect as long as Workers are allowed to talk to the rest of the world. A Worker could always communicate with a remote time server to measure time. Such communications will be far less accurate than a local timer, and since the timing differences are extremely small, they will be hard to measure this way. But, by using amplification techniques to improve the strength of the signal, repeating the attack many times and applying statistics, it could still be possible to derive secrets.
We therefore set out to develop an attack based on this approach. Upon applying the best techniques available to us, we were indeed able to produce a working Spectre variant 1 attack that could leak memory at a rate of 120 bits per hour. Compared to attacks demonstrated on many other platforms, 120 bits per hour is pretty slow. However, it’s obviously still fast enough to be a problem.
It’s important to note, though, that this speed was achieved in an ideal scenario:
Since the Workers Runtime prevents Workers from measuring their own execution time, any attack would need to rely on a remote time server. But for the purpose of our test, the “remote” server was in fact located on the same machine. In a real-world scenario, such a server would need to be accessed over the Internet, making the timing less accurate.
The machine running the test had no other load. A real-world machine would be processing hundreds or thousands of requests concurrently, creating noise.
The attack only demonstrated that it could read some bits that it shouldn’t. In order to read interesting bits, an attacker would first need to locate those bits, which likely would require reading hundreds or thousands of other bits first.
In the real world, these factors appear to make an attack too slow to be interesting. If an attack takes days or weeks to carry out, the contents of memory are highly likely to change before it can read them. For example, we update the Workers Runtime code at least once a week, which causes a restart of all processes.
That said, we did not feel comfortable relying on this argument as our defense. Instead, we set out to do better.
Part 2: Enhance our defenses
In the second part of the research, we designed and implemented a novel Spectre defense which we call Dynamic Process Isolation.
In short, our defense uses hardware performance counters to detect Workers whose performance characteristics could be indicative of an attack. Before the attack has had enough time to leak any bits, we move the Worker into a separate operating system process, thus taking advantage of the additional defenses implemented by the OS kernel. Crucially, since a benign Worker can still operate normally while in an isolated process, we are able to use a detector that produces false positives, as long as the rate is relatively low. This affordance made it possible for us to develop a working classifier where previous work in the area had struggled.
Specifically, we developed a detector based on measuring branch mispredictions. Spectre variant 1 attacks — the fastest and easiest kind of Spectre attack — work by fooling the CPU’s branch predictor to trigger speculative code execution. Such an attack, when running in our environment, must trigger repeated mispredictions in a loop, in order to get enough data to apply statistics to overcome the noise floor. We can see these mispredictions in the hardware performance counters. While an attack could try to evade the detector by spreading out its trials over a longer time period, doing so would slow down the attack by orders of magnitude, which is exactly our goal. Classifiers for other Spectre variants might be straightforward to build as well, however, we find other variants already produce much lower bandwidth or are otherwise effectively mitigated by our existing defenses.
This defense successfully detects and mitigates the attack we developed. We also tested it against a number of Spectre proofs of concept and found it caught all of them. Meanwhile, the rate of false positives is well within the range we can tolerate: Out of many thousands of Workers running on our platform, we see only about 20 being falsely detected as attacks.
Collaborating with TU Graz was a great experience. We are very happy to work with some of the world’s foremost experts on this problem, and to have produced not just an attack but also a constructive defense.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.