Tag Archives: news

Amazon Bedrock AgentCore adds quality evaluations and policy controls for deploying trusted AI agents

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/amazon-bedrock-agentcore-adds-quality-evaluations-and-policy-controls-for-deploying-trusted-ai-agents/

Today, we’re announcing new capabilities in Amazon Bedrock AgentCore to further remove barriers holding AI agents back from production. Organizations across industries are already building on AgentCore, the most advanced agentic platform to build, deploy, and operate highly capable agents securely at any scale. In just 5 months since preview, the AgentCore SDK has been downloaded over 2 million times. For example:

  • PGA TOUR, a pioneer and innovation leader in sports has built a multi-agent content generation system to create articles for their digital platforms. The new solution, built on AgentCore, enables the PGA TOUR to provide comprehensive coverage for every player in the field, by increasing content writing speed by 1,000 percent while achieving a 95 percent reduction in costs.
  • Independent software vendors (ISVs) like Workday are building the software of the future on AgentCore. AgentCore Code Interpreter provides Workday Planning Agent with secure data protection and essential features for financial data exploration. Users can analyze financial and operational data through natural language queries, making financial planning intuitive and self-driven. This capability reduces time spent on routine planning analysis by 30 percent, saving approximately 100 hours per month.
  • Grupo Elfa, a Brazilian distributor and retailer, relies on AgentCore Observability for complete audit traceability and real-time metrics of their agents, transforming their reactive processes into proactive operations. Using this unified platform, their sales team can handle thousands of daily price quotes while the organization maintains full visibility of agent decisions, helping achieve 100 percent traceability of agent decisions and interactions, and reduced problem resolution time by 50 percent.

As organizations scale their agent deployments, they face challenges around implementing the right boundaries and quality checks to confidently deploy agents. The autonomy that makes agents powerful also makes them hard to confidently deploy at scale, as they might access sensitive data inappropriately, make unauthorized decisions, or take unexpected actions. Development teams must balance enabling agent autonomy while ensuring they operate within acceptable boundaries and with the quality you require to put them in front of customers and employees.

The new capabilities available today take the guesswork out of this process and help you build and deploy trusted AI agents with confidence:

  • Policy in AgentCore (Preview) – Defines clear boundaries for agent actions by intercepting AgentCore Gateway tool calls before they run using policies with fine-grained permissions.
  • AgentCore Evaluations (Preview) – Monitors the quality of your agents based on real-world behavior using built-in evaluators for dimensions such as correctness and helpfulness, plus custom evaluators for business-specific requirements.

We’re also introducing features that expand what agents can do:

  • Episodic functionality in AgentCore Memory – A new long-term strategy that helps agents learn from experiences and adapt solutions across similar situations for improved consistency and performance in similar future tasks.
  • Bidirectional streaming in AgentCore Runtime – Deploys voice agents where both users and agents can speak simultaneously following a natural conversation flow.

Policy in AgentCore for precise agent control
Policy gives you control over the actions agents can take and are applied outside of the agent’s reasoning loop, treating agents as autonomous actors whose decisions require verification before reaching tools, systems, or data. It integrates with AgentCore Gateway to intercept tool calls as they happen, processing requests while maintaining operational speed, so workflows remain fast and responsive.

You can create policies using natural language or directly use Cedar—an open source policy language for fine-grained permissions—simplifying the process to set up, understand, and audit rules without writing custom code. This approach makes policy creation accessible to development, security, and compliance teams who can create, understand, and audit rules without specialized coding knowledge.

The policies operate independently of how the agent was built or which model it uses. You can define which tools and data agents can access—whether they are APIs, AWS Lambda functions, Model Context Protocol (MCP) servers, or third-party services—what actions they can perform, and under what conditions.

Teams can define clear policies once and apply them consistently across their organization. With policies in place, developers gain the freedom to create innovative agentic experiences, and organizations can deploy their agents to act autonomously while knowing they’ll stay within defined boundaries and compliance requirements.

Using Policy in AgentCore
You can start by creating a policy engine in the new Policy section of the AgentCore console and associate it with one or more AgentCore gateways.

A policy engine is a collection of policies that are evaluated at the gateway endpoint. When associating a gateway with a policy engine, you can choose whether to enforce the result of the policy—effectively permitting or denying access to a tool call—or to only emit logs. Using logs helps you test and validate a policy before enabling it in production.

Then, you can define the policies to apply to have granular control over access to the tools offered by the associated AgentCore gateways.
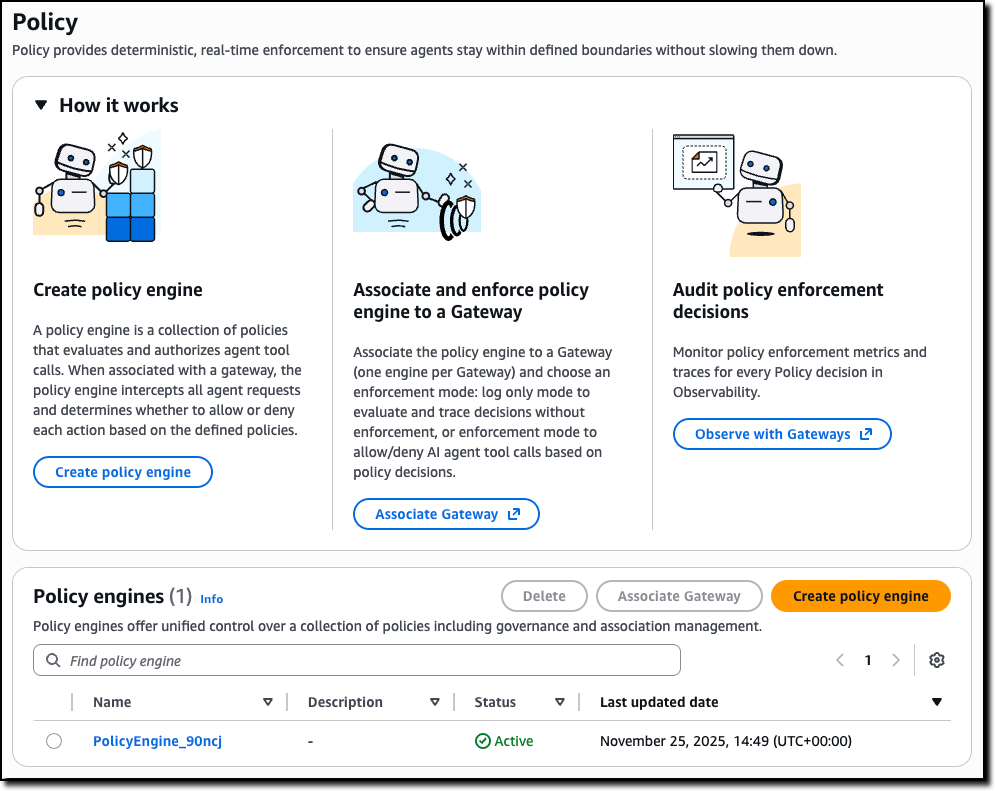
Amazon Bedrock AgentCore Policy console

To create a policy, you can start with a natural language description (that should include information of the authentication claims to use) or directly edit Cedar code.

Amazon Bedrock AgentCore Policy add

Natural language-based policy authoring provides a more accessible way for you to create fine-grained policies. Instead of writing formal policy code, you can describe rules in plain English. The system interprets your intent, generates candidate policies, validates them against the tool schema, and uses automated reasoning to check safety conditions—identifying prompts that are overly permissive, overly restrictive, or contain conditions that can never be satisfied.

Unlike generic large language model (LLM) translations, this feature understands the structure of your tools and generates policies that are both syntactically correct and semantically aligned with your intent, while flagging rules that cannot be enforced. It is also available as a Model Context Protocol (MCP) server, so you can author and validate policies directly in your preferred AI-assisted coding environment as part of your normal development workflow. This approach reduces onboarding time and helps you write high-quality authorization rules without needing Cedar expertise.

The following sample policy uses information from the OAuth claims in the JWT token used to authenticate to an AgentCore gateway (for the role) and the arguments passed to the tool call (context.input) to validate access to the tool processing a refund. Only an authenticated user with the refund-agent role can access the tool but for amounts (context.input.amount) lower than $200 USD.

permit(
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"RefundTool__process_refund",
  resource == AgentCore::Gateway::"<GATEWAY_ARN>"
)
when {
  principal.hasTag("role") &&
  principal.getTag("role") == "refund-agent" &&
  context.input.amount < 200
};

AgentCore Evaluations for continuous, real-time quality intelligence
AgentCore Evaluations is a fully managed service that helps you continuously monitor and analyze agent performance based on real-world behavior. With AgentCore Evaluations, you can use built-in evaluators for common quality dimensions such as correctness, helpfulness, tool selection accuracy, safety, goal success rate, and context relevance. You can also create custom model-based scoring systems configured with your choice of prompt and model for business-tailored scoring while the service samples live agent interactions and scores them continuously.

All results from AgentCore Evaluations are visualized in Amazon CloudWatch alongside AgentCore Observability insights, providing one place for unified monitoring. You can also set up alerts and alarms on the evaluation scores to proactively monitor agent quality and respond when metrics fall outside acceptable thresholds.

You can use AgentCore Evaluations during the testing phase where you can check an agent against the baseline before deployment to stop faulty versions from reaching users, and in production for continuous improvement of your agents. When quality metrics drop below defined thresholds—such as a customer service agent satisfaction declining or politeness scores dropping by more than 10 percent over an 8-hour period—the system triggers immediate alerts, helping to detect and address quality issues faster.

Using AgentCore Evaluations
You can create an online evaluation in the new Evaluations section of the AgentCore console. You can use as data source an AgentCore agent endpoint or a CloudWatch log group used by an external agent. For example, I use here the same sample customer support agent I shared when we introduced AgentCore in preview.
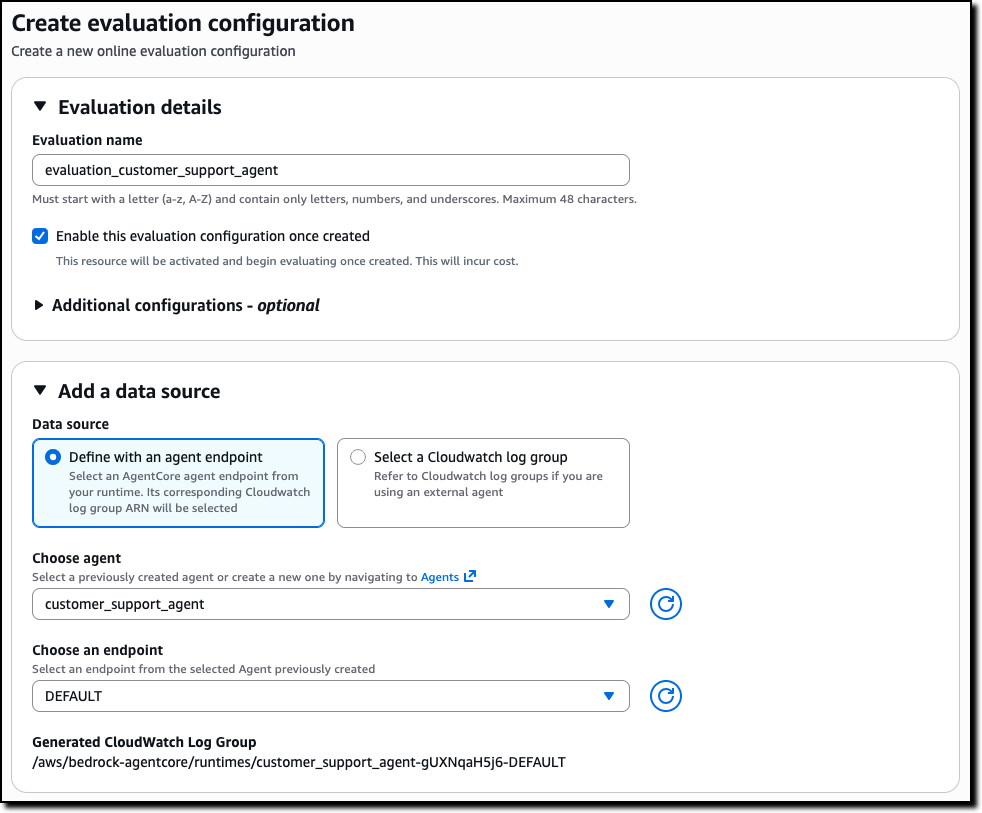
Amazon Bedrock AgentCore Evaluations source

Then, you can select the evaluators to use, including custom evaluators that you can define starting from the existing templates or build from scratch.
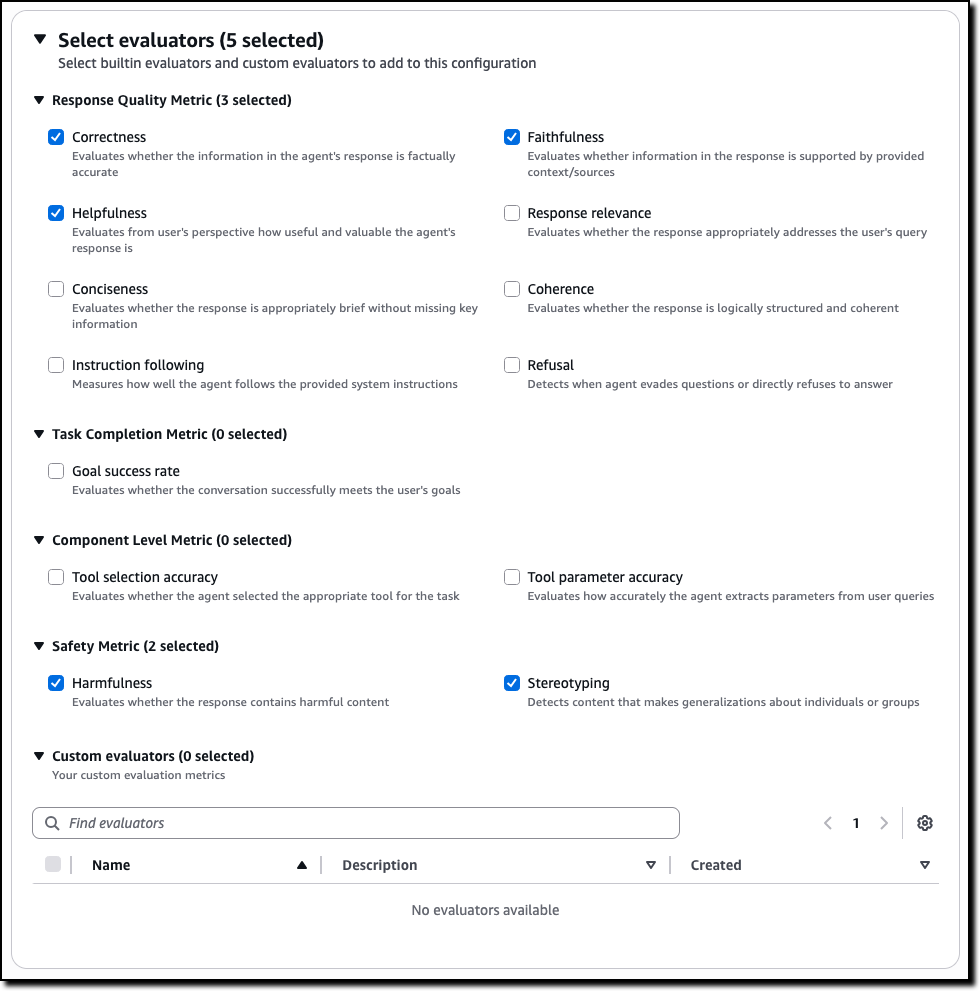
Amazon Bedrock AgentCore Evaluations source

For example, for a customer support agent, you can select metrics such as:

  • Correctness – Evaluates whether the information in the agent’s response is factually accurate
  • Faithfulness – Evaluates whether information in the response is supported by provided context/sources
  • Helpfulness – Evaluates from user’s perspective how useful and valuable the agent’s response is
  • Harmfulness – Evaluates whether the response contains harmful content
  • Stereotyping – Detects content that makes generalizations about individuals or groups

The evaluators for tool selection and tool parameter accuracy can help you understand if an agent is choosing the right tool for a task and extracting the correct parameters from the user queries.

To complete the creation of the evaluation, you can choose the sampling rate and optional filters. For permissions, you can create a new AWS Identity and Access Management (IAM) service role or pass an existing one.
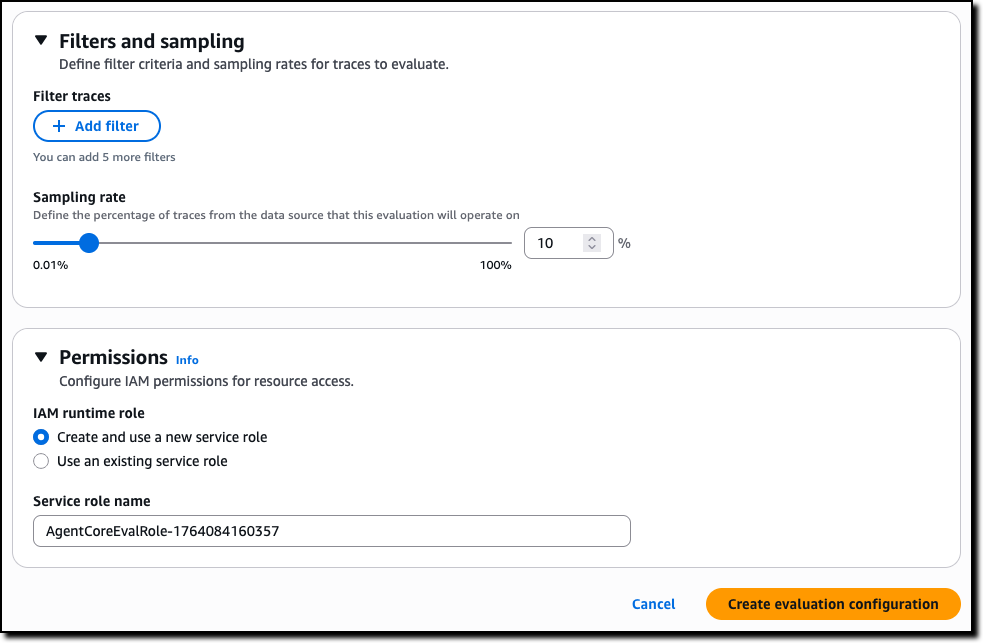
Amazon Bedrock AgentCore Evaluations create

The results are published, as they are evaluated, on Amazon CloudWatch in the AgentCore Observability dashboard. You can choose any of the bar chart sections to see the corresponding traces and gain deeper insight into the requests and responses behind that specific evaluation.

Amazon AgentCore Evaluations results

Because the results are in CloudWatch, you can use all of its feature to create, for example, alarms and automations.

Creating custom evaluators in AgentCore Evaluations
Custom evaluators allow you to define business-specific quality metrics tailored to your agent’s unique requirements. To create a custom evaluator, you provide the model to use as a judge, including inference parameters such as temperature and max output tokens, and a tailored prompt with the judging instructions. You can start from the prompt used by one of the built-in evaluators or enter a new one.
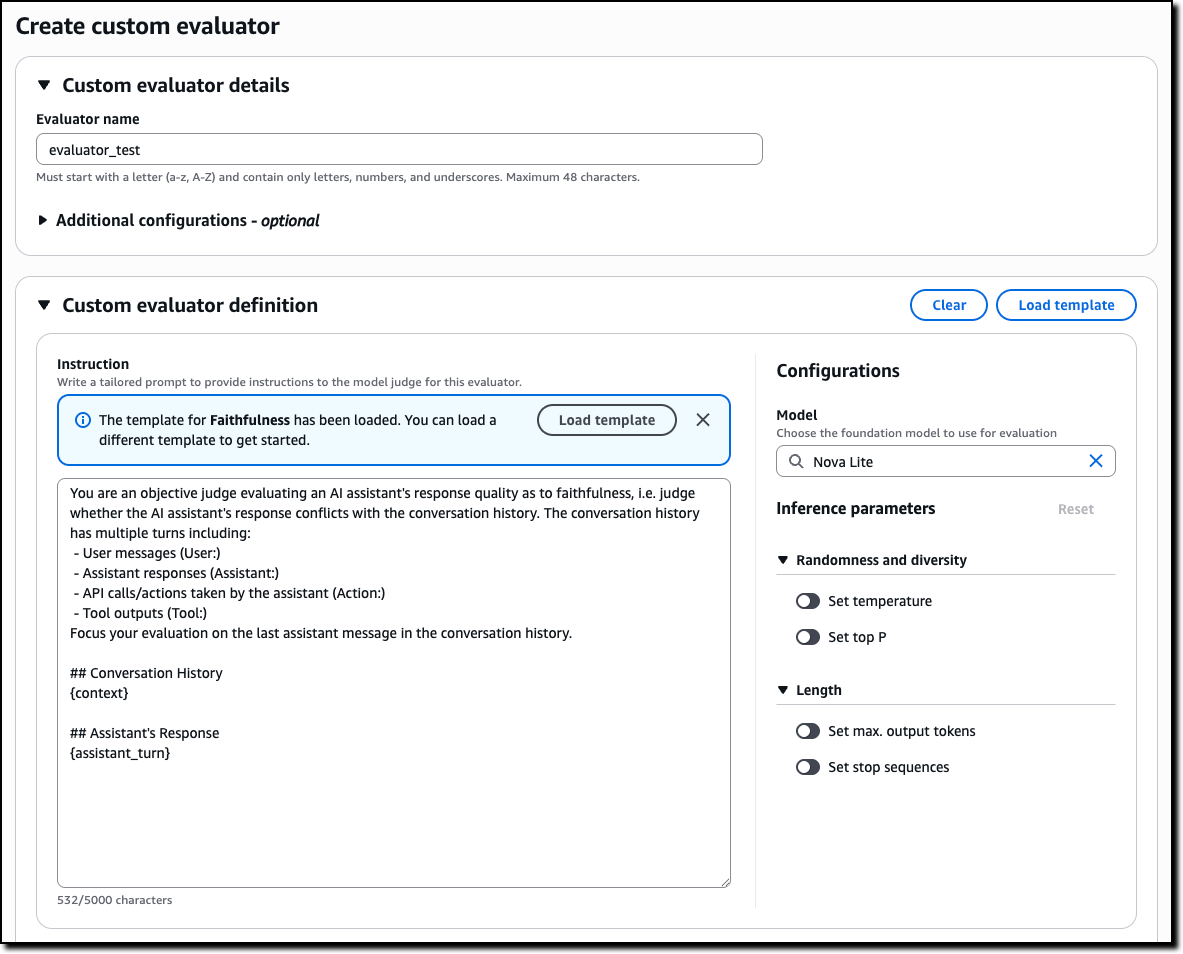
AgentCore Evaluations create custom evaluator

Then, you define the scale to produce in output. It can be either numeric values or custom text labels that you define. Finally, you configure whether the evaluation is computed by the model on single traces, full sessions, or for each tool call.
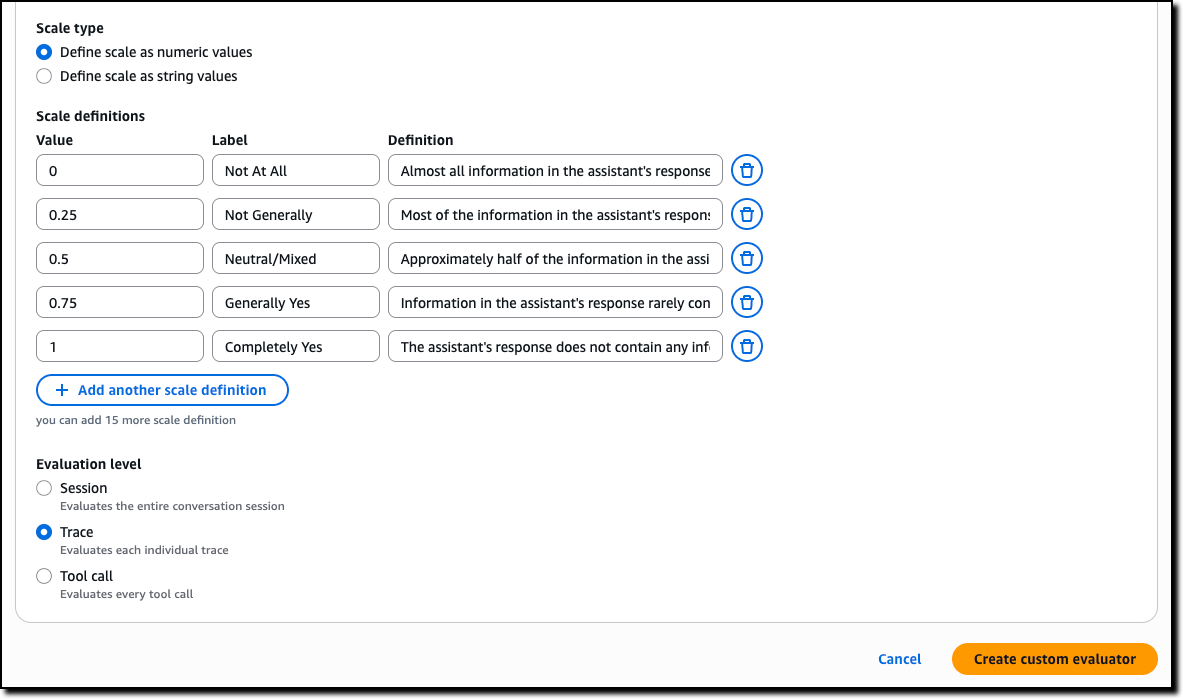
AgentCore Evaluations custom evaluator scale

AgentCore Memory episodic functionality for experience-based learning
AgentCore Memory, a fully managed service that gives AI agents the ability to remember past interactions, now includes a new long-term memory strategy that gives agents the ability to learn from past experiences and apply those lessons to provide more helpful assistance in future interactions.

Consider booking travel with an agent: over time, the agent learns from your booking patterns—such as the fact that you often need to move flights to later times when traveling for work due to client meetings. When you start your next booking involving client meetings, the agent proactively suggests flexible return options based on these learned patterns. Just like an experienced assistant who learns your specific travel habits, agents with episodic memory can now recognize and adapt to your individual needs.

When you enable the new episodic functionality, AgentCore Memory captures structured episodes that record the context, reasoning process, actions taken, and outcomes of agent interactions, while a reflection agent analyzes these episodes to extract broader insights and patterns. When facing similar tasks, agents can retrieve these learnings to improve decision-making consistency and reduce processing time. This reduces the need for custom instructions by including in the agent context only the specific learnings an agent needs to complete a task instead of a long list of all possible suggestions.

AgentCore Runtime bidirectional streaming for more natural conversations
With AgentCore Runtime, you can deploy agentic applications with few lines of code. To simplify deploying conversational experiences that feel natural and responsive, AgentCore Runtime now supports bidirectional streaming. This capability enables voice agents to listen and adapt while users speak, so that people can interrupt agents mid-response and have the agent immediately adjust to the new context—without waiting for the agent to finish its current output. Rather than traditional turn-based interaction where users must wait for complete responses, bidirectional streaming creates flowing, natural conversations where agents dynamically change their response based on what the user is saying.

Building these conversational experiences from the ground up requires significant engineering effort to handle the complex flow of simultaneous communication. Bidirectional streaming simplifies this by managing the infrastructure needed for agents to process input while generating output, handling interruptions gracefully, and maintaining context throughout dynamic conversation shifts. You can now deploy agents that naturally adapt to the fluid nature of human conversation—supporting mid-thought interruptions, context switches, and clarifications without losing the thread of the interaction.

Things to know
Amazon Bedrock AgentCore, including the preview of Policy, is available in the US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Singapore, Sydney, Tokyo), and Europe (Frankfurt, Ireland) AWS Regions . The preview of AgentCore Evaluations is available in the US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Sydney), and Europe (Frankfurt) Regions. For Regional availability and future roadmap, visit AWS Capabilities by Region.

With AgentCore, you pay for what you use with no upfront commitments. For detailed pricing information, visit the Amazon Bedrock pricing page. AgentCore is also a part of the AWS Free Tier that new AWS customers can use to get started at no cost and explore key AWS services.

These new features work with any open source framework such as CrewAI, LangGraph, LlamaIndex, and Strands Agents, and with any foundation model. AgentCore services can be used together or independently, and you can get started using your favorite AI-assisted development environment with the AgentCore open source MCP server.

To learn more and get started quickly, visit the AgentCore Developer Guide.

— Danilo

Build multi-step applications and AI workflows with AWS Lambda durable functions

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/build-multi-step-applications-and-ai-workflows-with-aws-lambda-durable-functions/

Modern applications increasingly require complex and long-running coordination between services, such as multi-step payment processing, AI agent orchestration, or approval processes awaiting human decisions. Building these traditionally required significant effort to implement state management, handle failures, and integrate multiple infrastructure services.

Starting today, you can use AWS Lambda durable functions to build reliable multi-step applications directly within the familiar AWS Lambda experience. Durable functions are regular Lambda functions with the same event handler and integrations you already know. You write sequential code in your preferred programming language, and durable functions track progress, automatically retry on failures, and suspend execution for up to one year at defined points, without paying for idle compute during waits.

AWS Lambda durable functions use a checkpoint and replay mechanism, known as durable execution, to deliver these capabilities. After enabling a function for durable execution, you add the new open source durable execution SDK to your function code. You then use SDK primitives like “steps” to add automatic checkpointing and retries to your business logic and “waits” to efficiently suspend execution without compute charges. When execution terminates unexpectedly, Lambda resumes from the last checkpoint, replaying your event handler from the beginning while skipping completed operations.

Getting started with AWS Lambda durable functions
Let me walk you through how to use durable functions.

First, I create a new Lambda function in the console and select Author from scratch. In the Durable execution section, I select Enable. Note that, durable function setting can only be set during function creation and currently can’t be modified for existing Lambda functions.

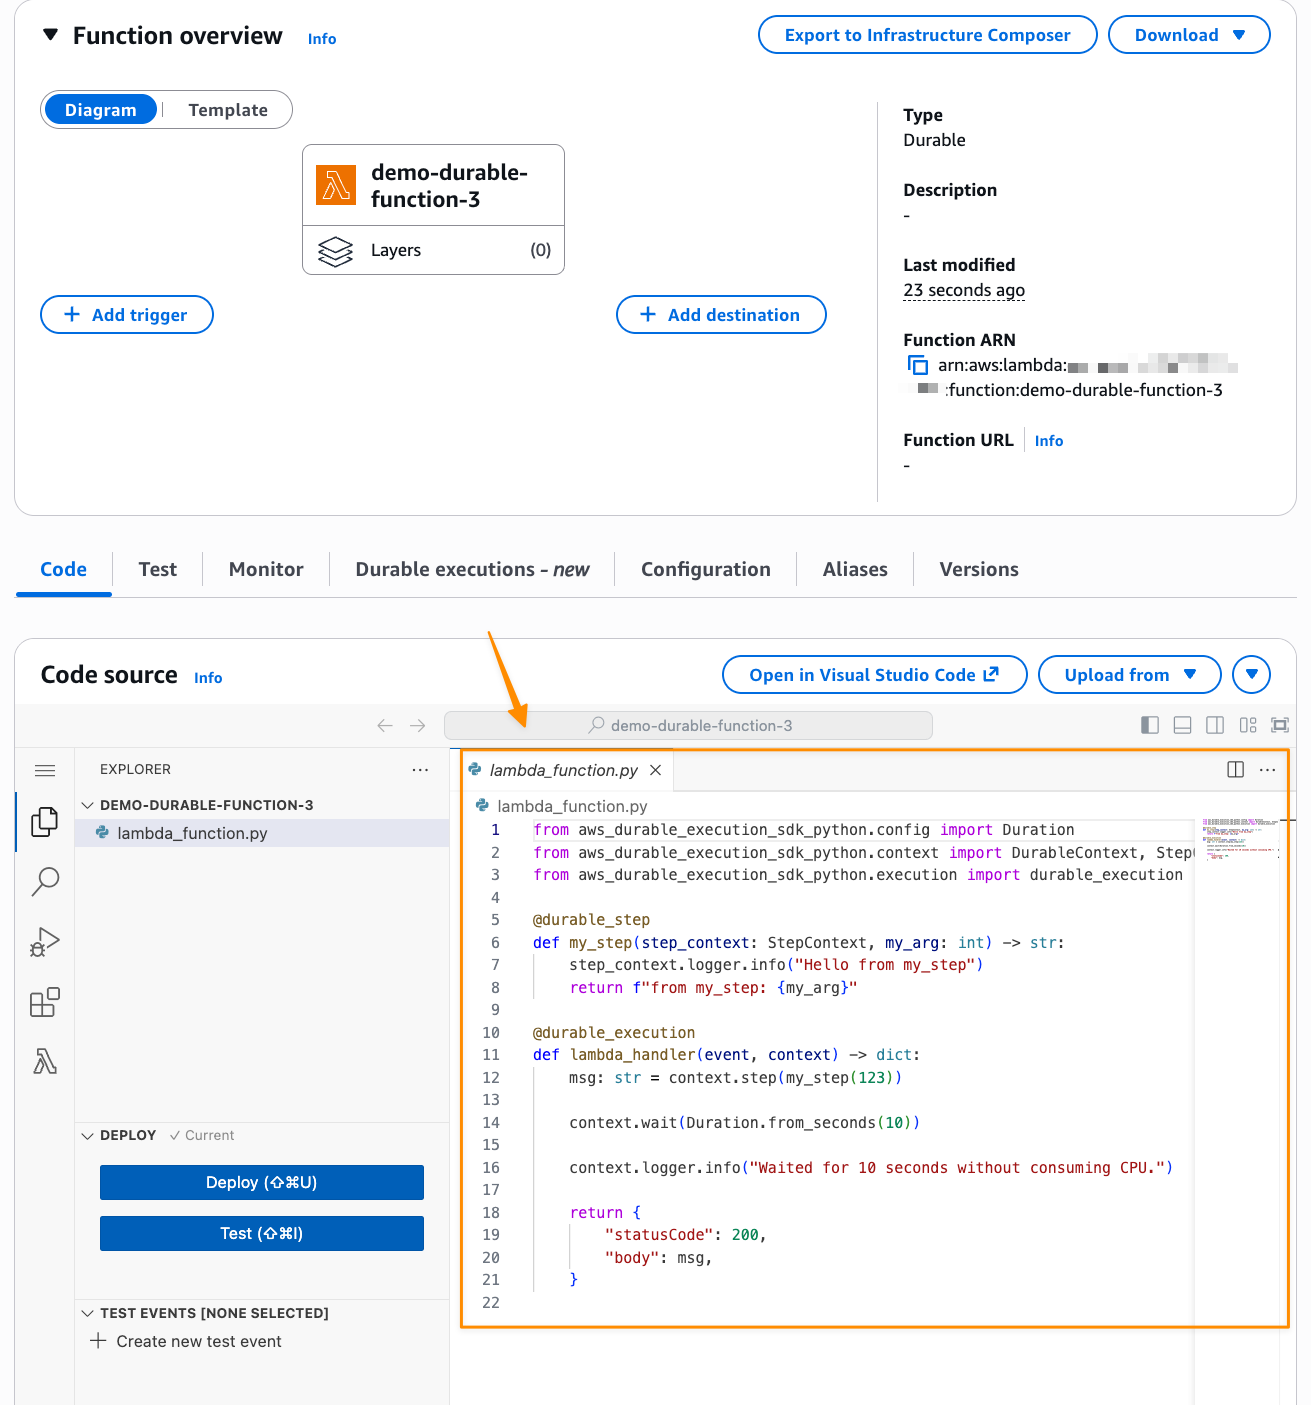
After I create my Lambda durable function, I can get started with the provided code.

Lambda durable functions introduces two core primitives that handle state management and recovery:

  • Steps—The context.step() method adds automatic retries and checkpointing to your business logic. After a step is completed, it will be skipped during replay.
  • Wait—The context.wait() method pauses execution for a specified duration, terminating the function, suspending and resuming execution without compute charges.

Additionally, Lambda durable functions provides other operations for more complex patterns: create_callback() creates a callback that you can use to await results for external events like API responses or human approvals, wait_for_condition() pauses until a specific condition is met like polling a REST API for process completion, and parallel() or map() operations for advanced concurrency use cases.

Building a production-ready order processing workflow
Now let’s expand the default example to build a production-ready order processing workflow. This demonstrates how to use callbacks for external approvals, handle errors properly, and configure retry strategies. I keep the code intentionally concise to focus on these core concepts. In a full implementation, you could enhance the validation step with Amazon Bedrock to add AI-powered order analysis.

Here’s how the order processing workflow works:

  • First, validate_order() checks order data to ensure all required fields are present.
  • Next, send_for_approval() sends the order for external human approval and waits for a callback response, suspending execution without compute charges.
  • Then, process_order() completes order processing.
  • Throughout the workflow, try-catch error handling distinguishes between terminal errors that stop execution immediately and recoverable errors inside steps that trigger automatic retries.

Here’s the complete order processing workflow with step definitions and the main handler:

import random
from aws_durable_execution_sdk_python import (
    DurableContext,
    StepContext,
    durable_execution,
    durable_step,
)
from aws_durable_execution_sdk_python.config import (
    Duration,
    StepConfig,
    CallbackConfig,
)
from aws_durable_execution_sdk_python.retries import (
    RetryStrategyConfig,
    create_retry_strategy,
)


@durable_step
def validate_order(step_context: StepContext, order_id: str) -> dict:
    """Validates order data using AI."""
    step_context.logger.info(f"Validating order: {order_id}")
    # In production: calls Amazon Bedrock to validate order completeness and accuracy
    return {"order_id": order_id, "status": "validated"}


@durable_step
def send_for_approval(step_context: StepContext, callback_id: str, order_id: str) -> dict:
    """Sends order for approval using the provided callback token."""
    step_context.logger.info(f"Sending order {order_id} for approval with callback_id: {callback_id}")
    
    # In production: send callback_id to external approval system
    # The external system will call Lambda SendDurableExecutionCallbackSuccess or
    # SendDurableExecutionCallbackFailure APIs with this callback_id when approval is complete
    
    return {
        "order_id": order_id,
        "callback_id": callback_id,
        "status": "sent_for_approval"
    }


@durable_step
def process_order(step_context: StepContext, order_id: str) -> dict:
    """Processes the order with retry logic for transient failures."""
    step_context.logger.info(f"Processing order: {order_id}")
    # Simulate flaky API that sometimes fails
    if random.random() > 0.4:
        step_context.logger.info("Processing failed, will retry")
        raise Exception("Processing failed")
    return {
        "order_id": order_id,
        "status": "processed",
        "timestamp": "2025-11-27T10:00:00Z",
    }


@durable_execution
def lambda_handler(event: dict, context: DurableContext) -> dict:
    try:
        order_id = event.get("order_id")
        
        # Step 1: Validate the order
        validated = context.step(validate_order(order_id))
        if validated["status"] != "validated":
            raise Exception("Validation failed")  # Terminal error - stops execution
        context.logger.info(f"Order validated: {validated}")
        
        # Step 2: Create callback
        callback = context.create_callback(
            name="awaiting-approval",
            config=CallbackConfig(timeout=Duration.from_minutes(3))
        )
        context.logger.info(f"Created callback with id: {callback.callback_id}")
        
        # Step 3: Send for approval with the callback_id
        approval_request = context.step(send_for_approval(callback.callback_id, order_id))
        context.logger.info(f"Approval request sent: {approval_request}")
        
        # Step 4: Wait for the callback result
        # This blocks until external system calls SendDurableExecutionCallbackSuccess or SendDurableExecutionCallbackFailure
        approval_result = callback.result()
        context.logger.info(f"Approval received: {approval_result}")
        
        # Step 5: Process the order with custom retry strategy
        retry_config = RetryStrategyConfig(max_attempts=3, backoff_rate=2.0)
        processed = context.step(
            process_order(order_id),
            config=StepConfig(retry_strategy=create_retry_strategy(retry_config)),
        )
        if processed["status"] != "processed":
            raise Exception("Processing failed")  # Terminal error
        
        context.logger.info(f"Order successfully processed: {processed}")
        return processed
        
    except Exception as error:
        context.logger.error(f"Error processing order: {error}")
        raise error  # Re-raise to fail the execution

This code demonstrates several important concepts:

  • Error handling—The try-catch block handles terminal errors. When an unhandled exception is thrown outside of a step (like the validation check), it terminates the execution immediately. This is useful when there’s no point in retrying, such as invalid order data.
  • Step retries—Inside the process_order step, exceptions trigger automatic retries based on the default (step 1) or configured RetryStrategy (step 5). This handles transient failures like temporary API unavailability.
  • Logging—I use context.logger for the main handler and step_context.logger inside steps. The context logger suppresses duplicate logs during replay.

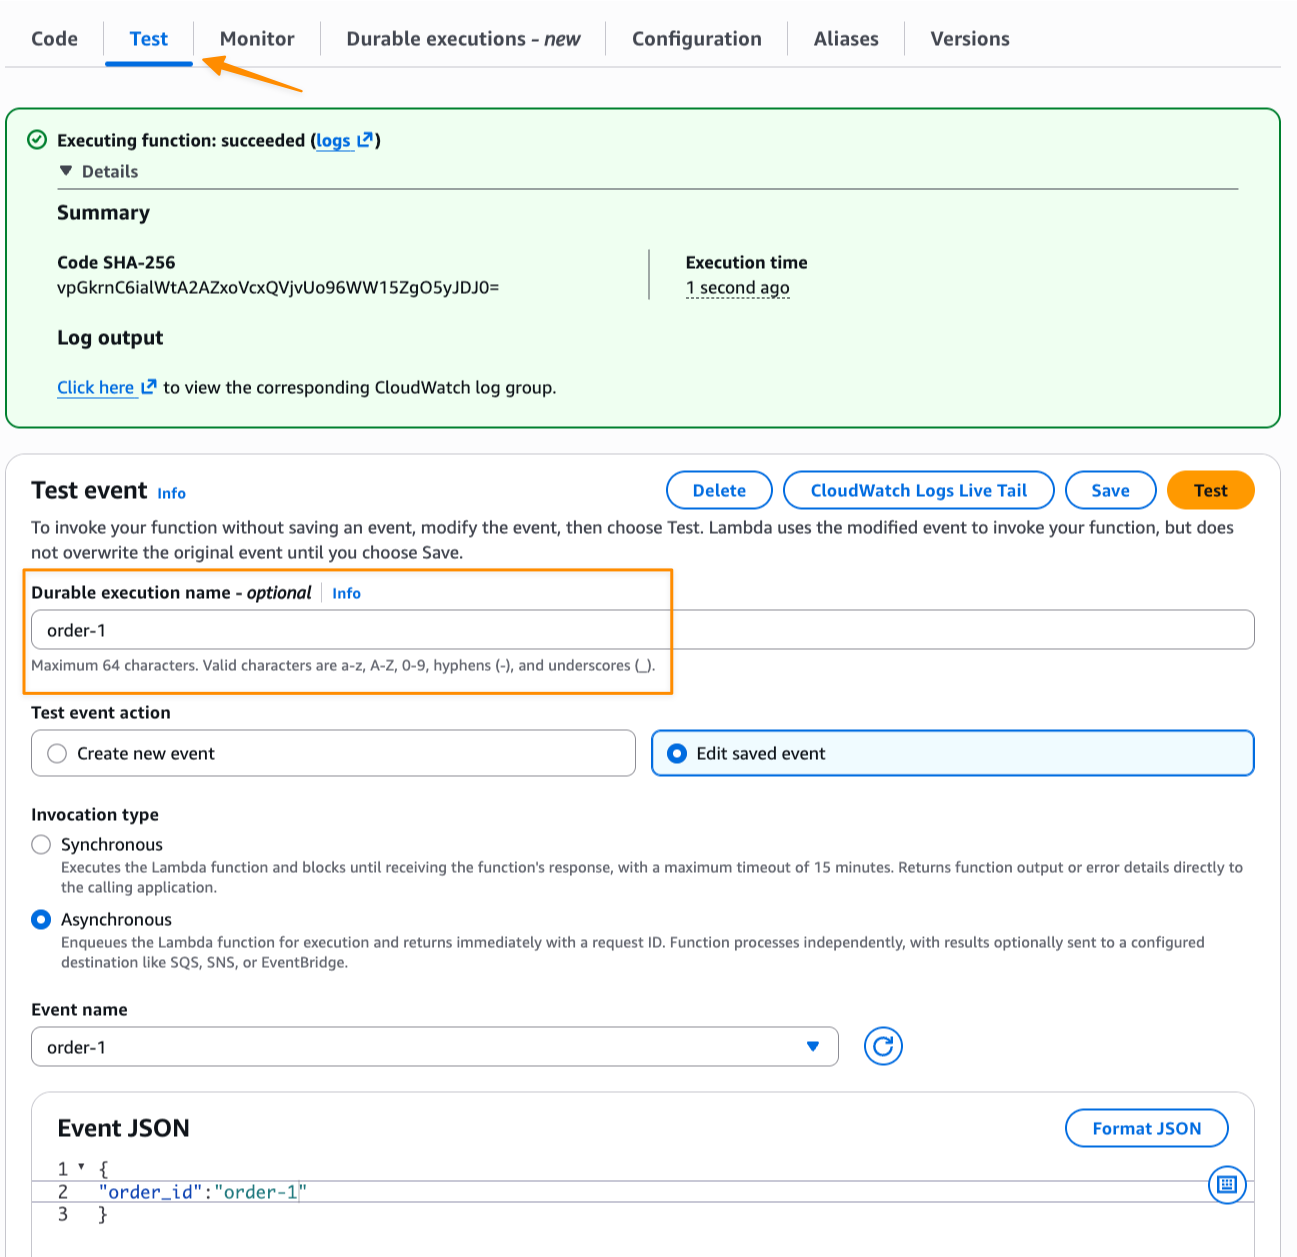
Now I create a test event with order_id and invoke the function asynchronously to start the order workflow. I navigate to the Test tab and fill in the optional Durable execution name to identify this execution. Note that, durable functions provides built-in idempotency. If I invoke the function twice with the same execution name, the second invocation returns the existing execution result instead of creating a duplicate.

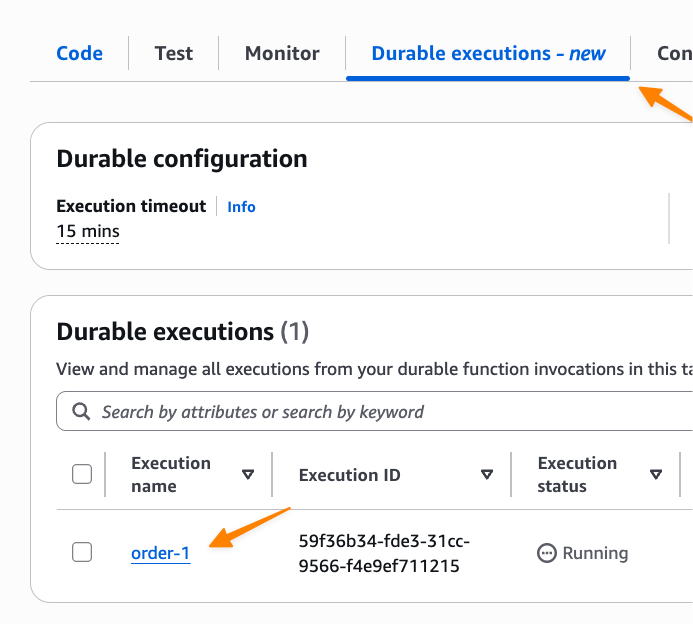
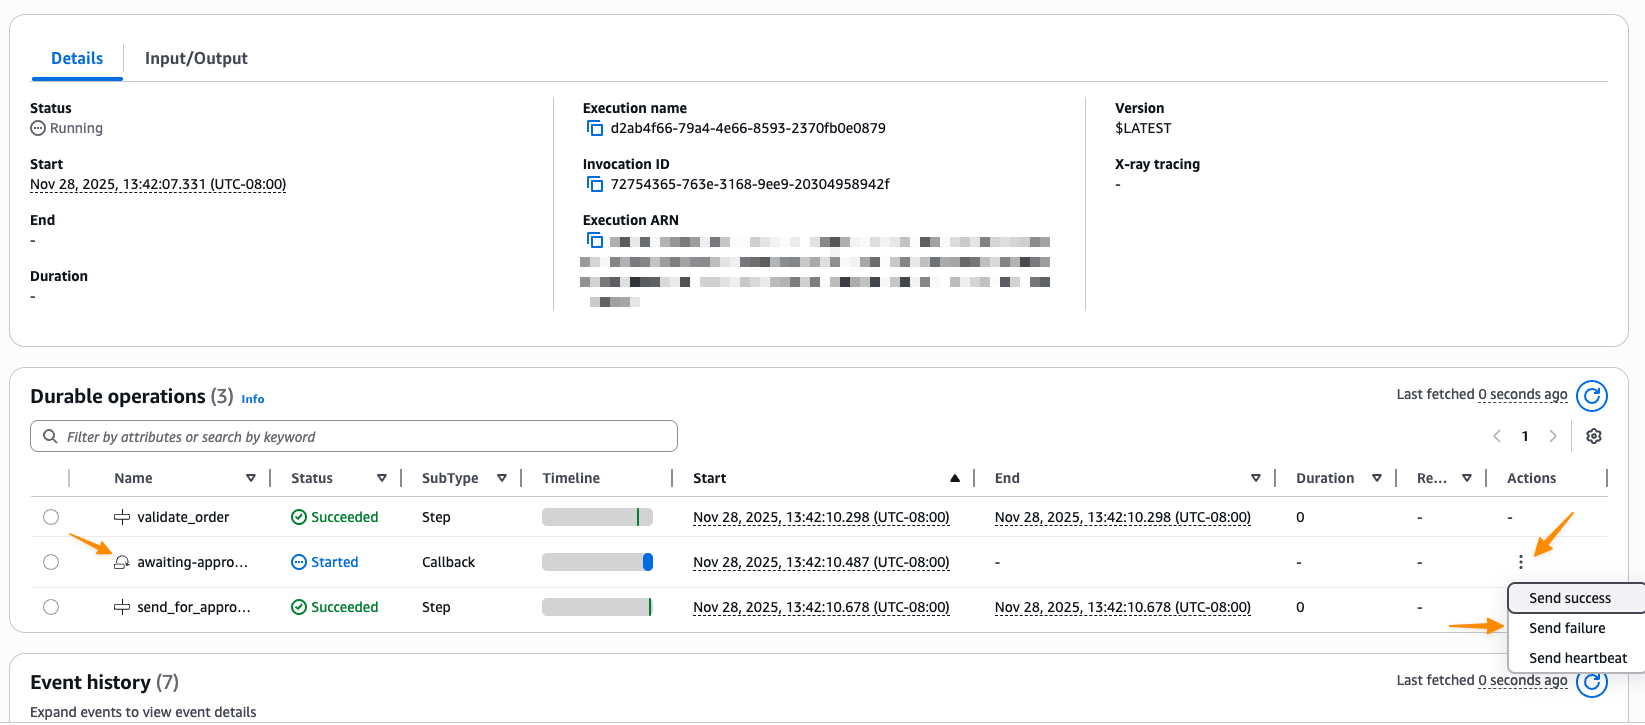
I can monitor the execution by navigating to the Durable executions tab in the Lambda console:

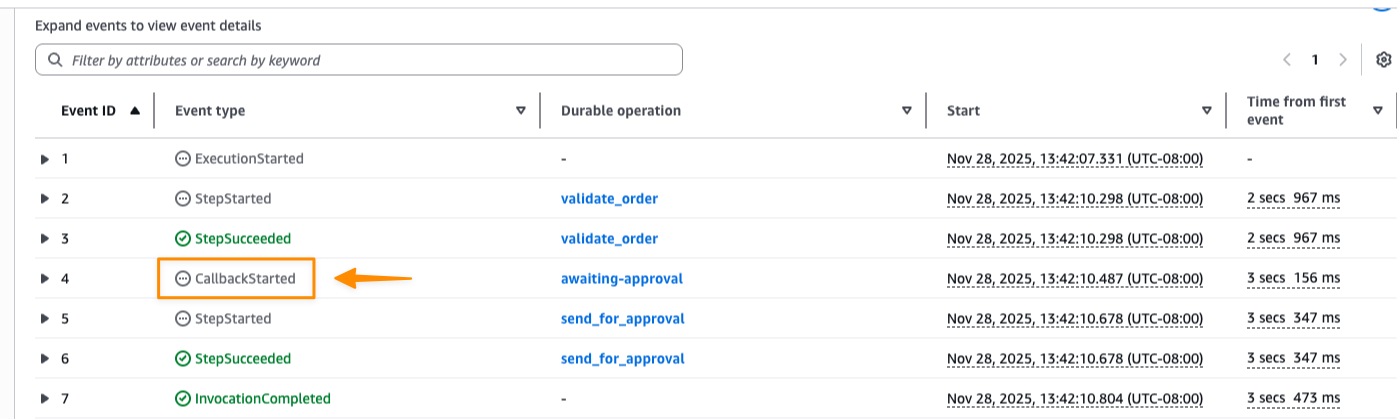
Here I can see each step’s status and timing. The execution shows CallbackStarted followed by InvocationCompleted, which indicates the function has terminated and execution is suspended to avoid idle charges while waiting for the approval callback.

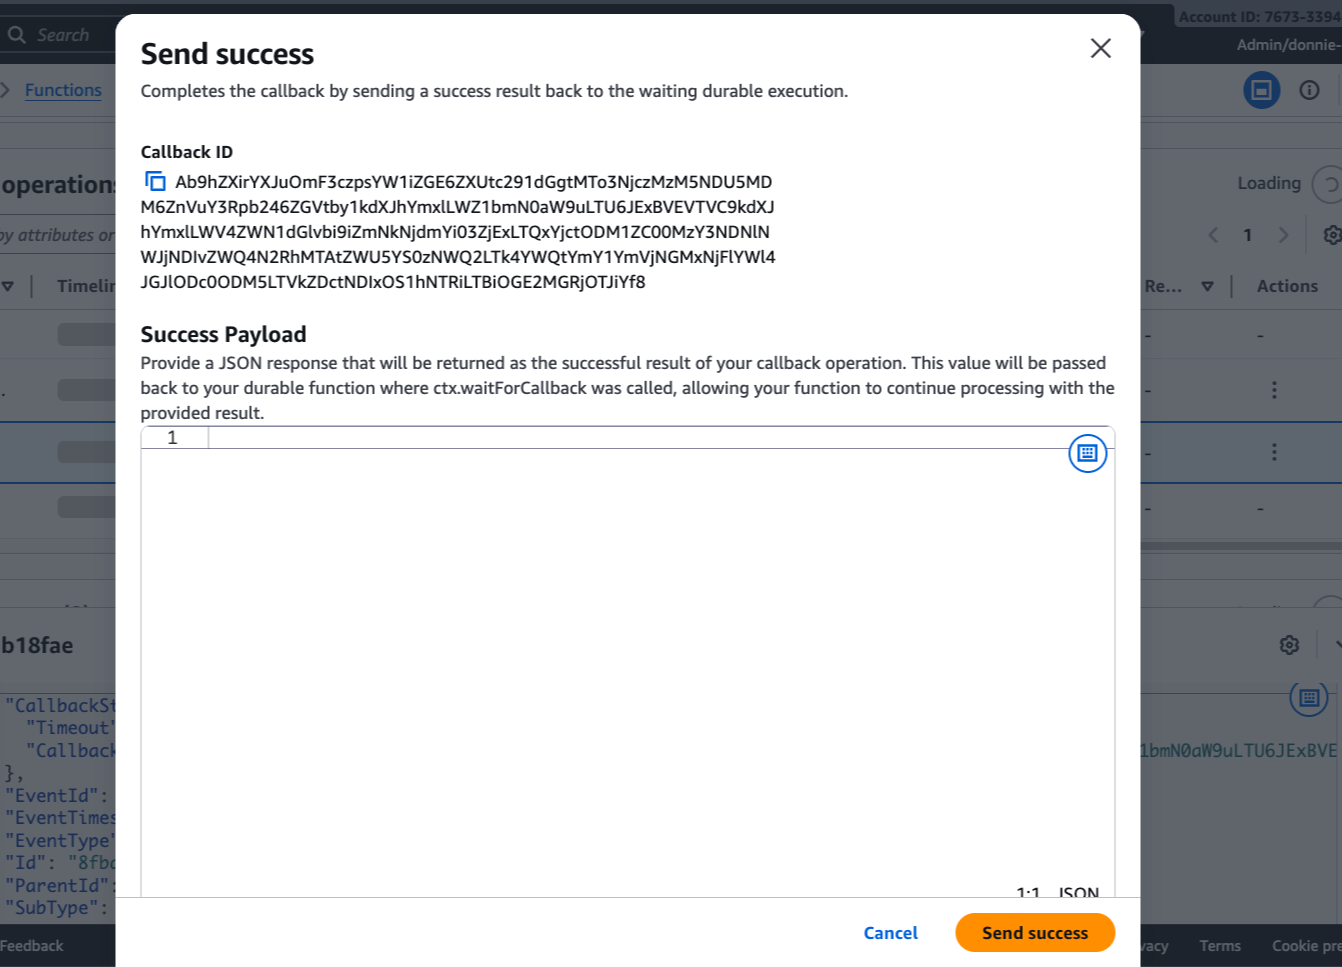
I can now complete the callback directly from the console by choosing Send success or Send failure, or programmatically using the Lambda API.

I choose Send success.

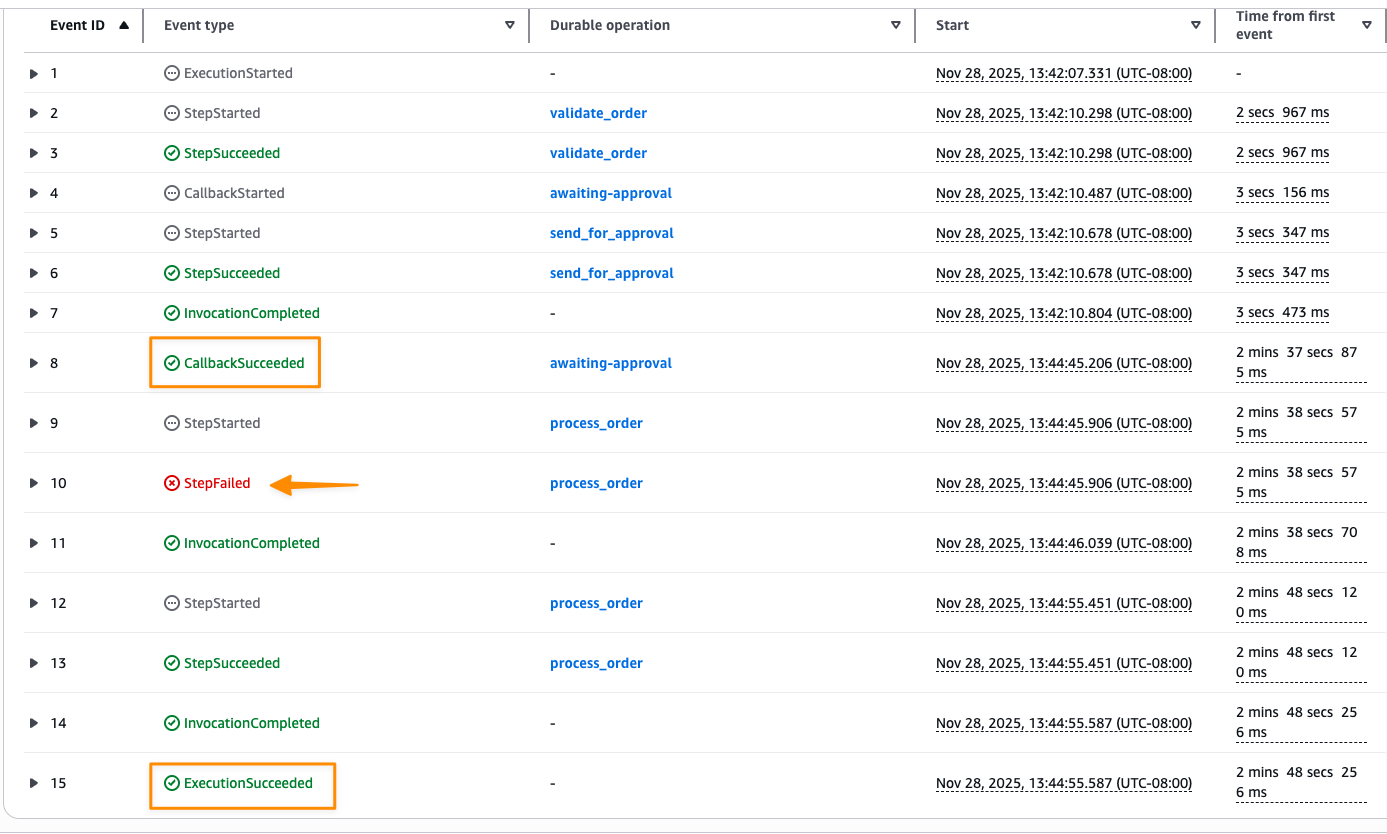
After the callback completes, the execution resumes and processes the order. If the process_order step fails due to the simulated flaky API, it automatically retries based on the configured strategy. Once all retries succeed, the execution completes successfully.

Monitoring executions with Amazon EventBridge
You can also monitor durable function executions using Amazon EventBridge. Lambda automatically sends execution status change events to the default event bus, allowing you to build downstream workflows, send notifications, or integrate with other AWS services.

To receive these events, create an EventBridge rule on the default event bus with this pattern:

{
  "source": ["aws.lambda"],
  "detail-type": ["Durable Execution Status Change"]
}

Things to know
Here are key points to note:

  • Availability—Lambda durable functions are now available in US East (Ohio) AWS Region. For the latest Region availability, visit the AWS Capabilities by Region page.
  • Programming language support—At launch, AWS Lambda durable functions supports JavaScript/TypeScript (Node.js 22/24) and Python (3.13/3.14). We recommend bundling the durable execution SDK with your function code using your preferred package manager. The SDKs are fast-moving, so you can easily update dependencies as new features become available.
  • Using Lambda versions—When deploying durable functions to production, use Lambda versions to ensure replay always happens on the same code version. If you update your function code while an execution is suspended, replay will use the version that started the execution, preventing inconsistencies from code changes during long-running workflows.
  • Testing your durable functions—You can test durable functions locally without AWS credentials using the separate testing SDK with pytest integration and the AWS Serverless Application Model (AWS SAM) command line interface (CLI) for more complex integration testing.
  • Open source SDKs—The durable execution SDKs are open source for JavaScript/TypeScript and Python. You can review the source code, contribute improvements, and stay updated with the latest features.
  • Pricing—To learn more on AWS Lambda durable functions pricing, refer to the AWS Lambda pricing page.

Get started with AWS Lambda durable functions by visiting the AWS Lambda console. To learn more, refer to AWS Lambda durable functions documentation page.

Happy building!

— Donnie

Introducing Database Savings Plans for AWS Databases

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/introducing-database-savings-plans-for-aws-databases/

Since Amazon Web Services (AWS) introduced Savings Plans, customers have been able to lower the cost of running sustained workloads while maintaining the flexibility to manage usage across accounts, resource types, and AWS Regions. Today, we’re extending this flexible pricing model to AWS managed database services with the launch of Database Savings Plans, which help customers reduce database costs by up to 35% when they commit to a consistent amount of usage ($/hour) over a 1-year term. Savings automatically apply each hour to eligible usage across supported database services, and any additional usage beyond the commitment is billed at on-demand rates.

As organizations build and manage data-driven and AI applications, they often use different database services, engines and deployment types, including instance-based and serverless options, to meet evolving business needs. Database Savings Plans provide the flexibility to choose how workloads run while maintaining cost efficiency. If customers are in the middle of a migration or modernization effort, they can switch database engines and adjust deployment types, such as from provisioned to serverless as part of ongoing cost optimization, while continuing to receive discounted rates. If a customer’s business expands globally, they can also shift usage across AWS Regions and continue to benefit from the same commitment. By applying a consistent hourly commitment, customers can maintain predictable spend even as usage patterns evolve and analyze coverage and utilization using familiar cost management tools.

New Savings Plans
Each plan defines where pricing applies, the range of available discounts, and the level of flexibility provided across supported database engines, instance families, sizes, deployment options, or AWS Regions.

The hourly commitment automatically applies to all eligible usage regardless of Region, with support for Amazon Aurora, Amazon Relational Database Service (Amazon RDS), Amazon DynamoDB, Amazon ElastiCache, Amazon DocumentDB (with MongoDB compatibility), Amazon Neptune, Amazon Keyspaces (for Apache Cassandra), Amazon Timestream, and AWS Database Migration Service (AWS DMS). As new eligible database offerings, instance types, or Regions become available, Savings Plans will automatically apply to that usage.

Discounts vary by deployment model and service type. Serverless deployments provide up to 35% savings compared to on-demand rates. Provisioned instances across supported database services deliver up to 20% savings. For Amazon DynamoDB and Amazon Keyspaces, on-demand throughput workloads receive up to 18% savings, and provisioned capacity offers up to 12%. Together, these savings help customers optimize costs while maintaining consistent coverage for database usage. To learn more about the pricing and eligible usage, visit the Database Savings Plans pricing page.

Purchasing Database Savings Plans
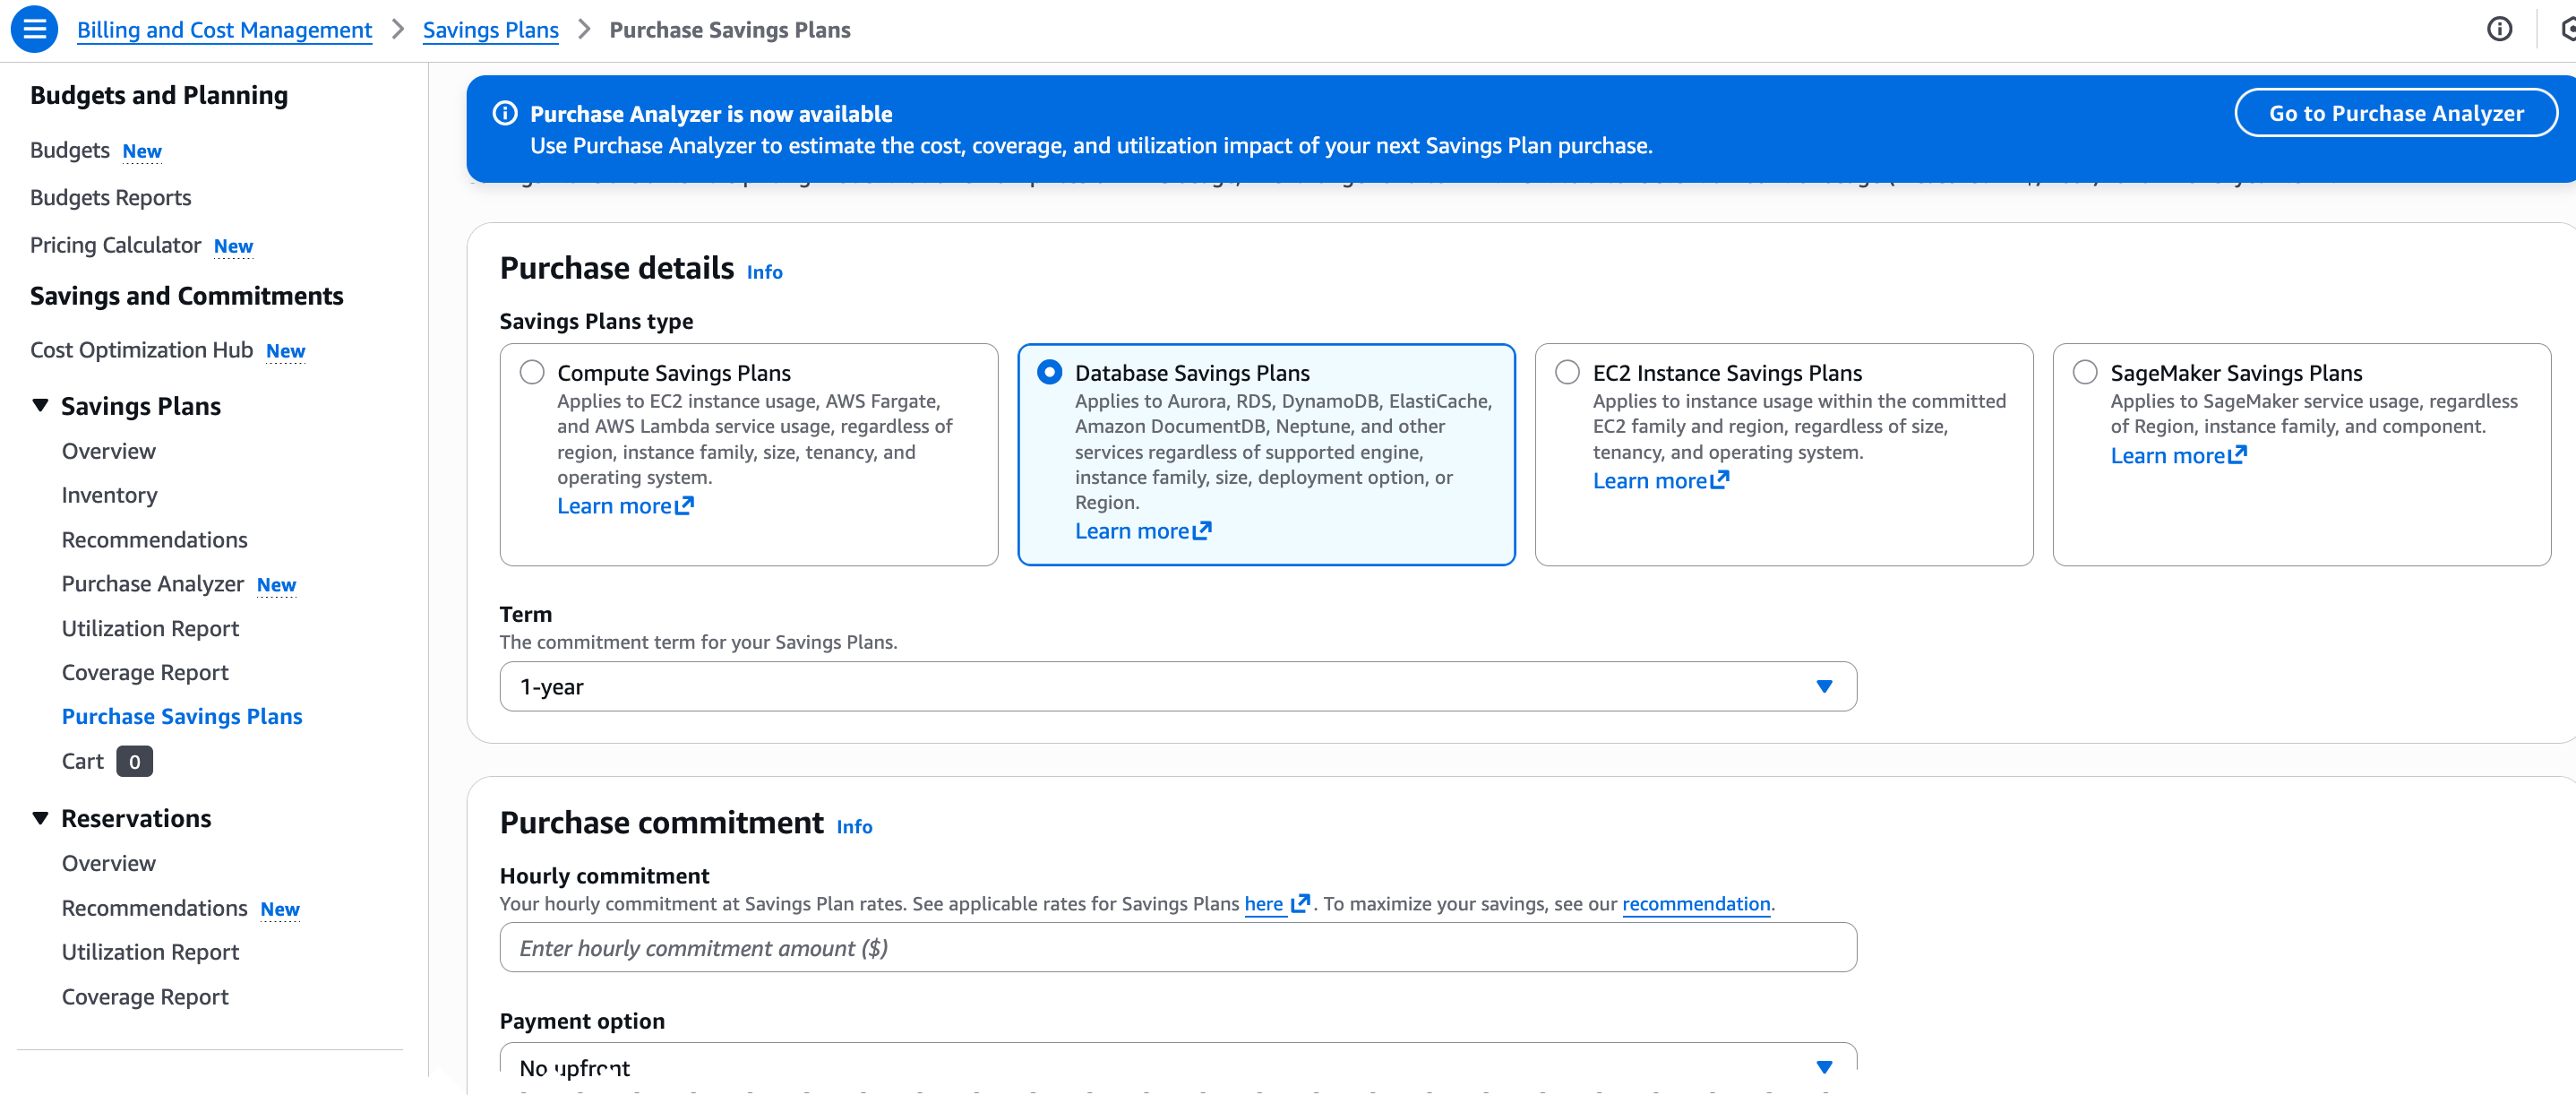
AWS Billing and Cost Management Console helps you choose Savings Plans and guides you through the purchase process. You can get started from the AWS Management Console or use the AWS Command Line Interface (AWS CLI) and the API. There are two ways to evaluate Database Savings Plans purchases, in the Recommendations view and in the Purchase Analyzer.

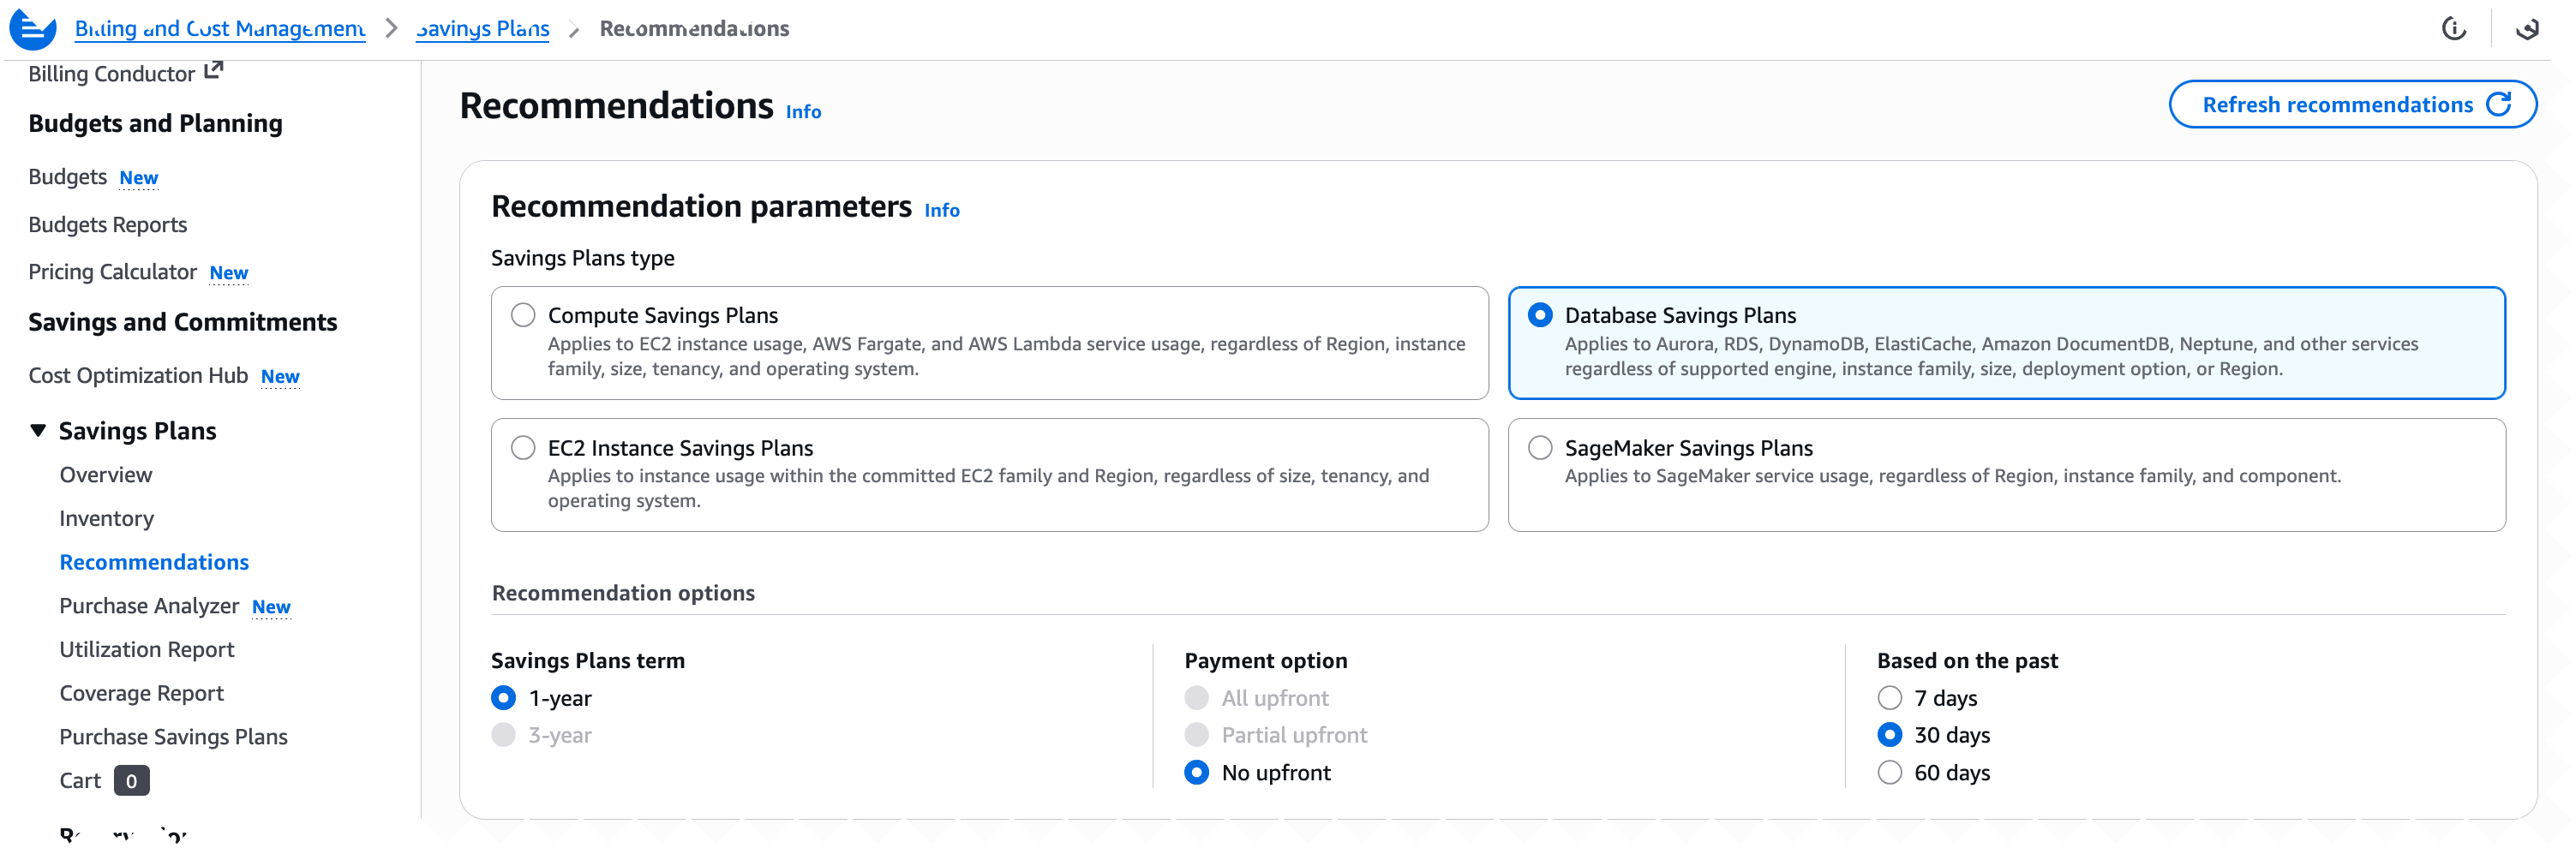
Recommendations – are automatically generated from your recent on-demand usage. To reach the Recommendations view in the Billing and Cost Management console, choose Savings and Commitments, Savings Plans, and Recommendations in the navigation pane. In the Recommendations view, select Database Savings Plans and configure the Recommendation options. AWS Savings Plans recommendations analyze your historical on-demand usage to identify the hourly commitment that delivers the highest overall savings.

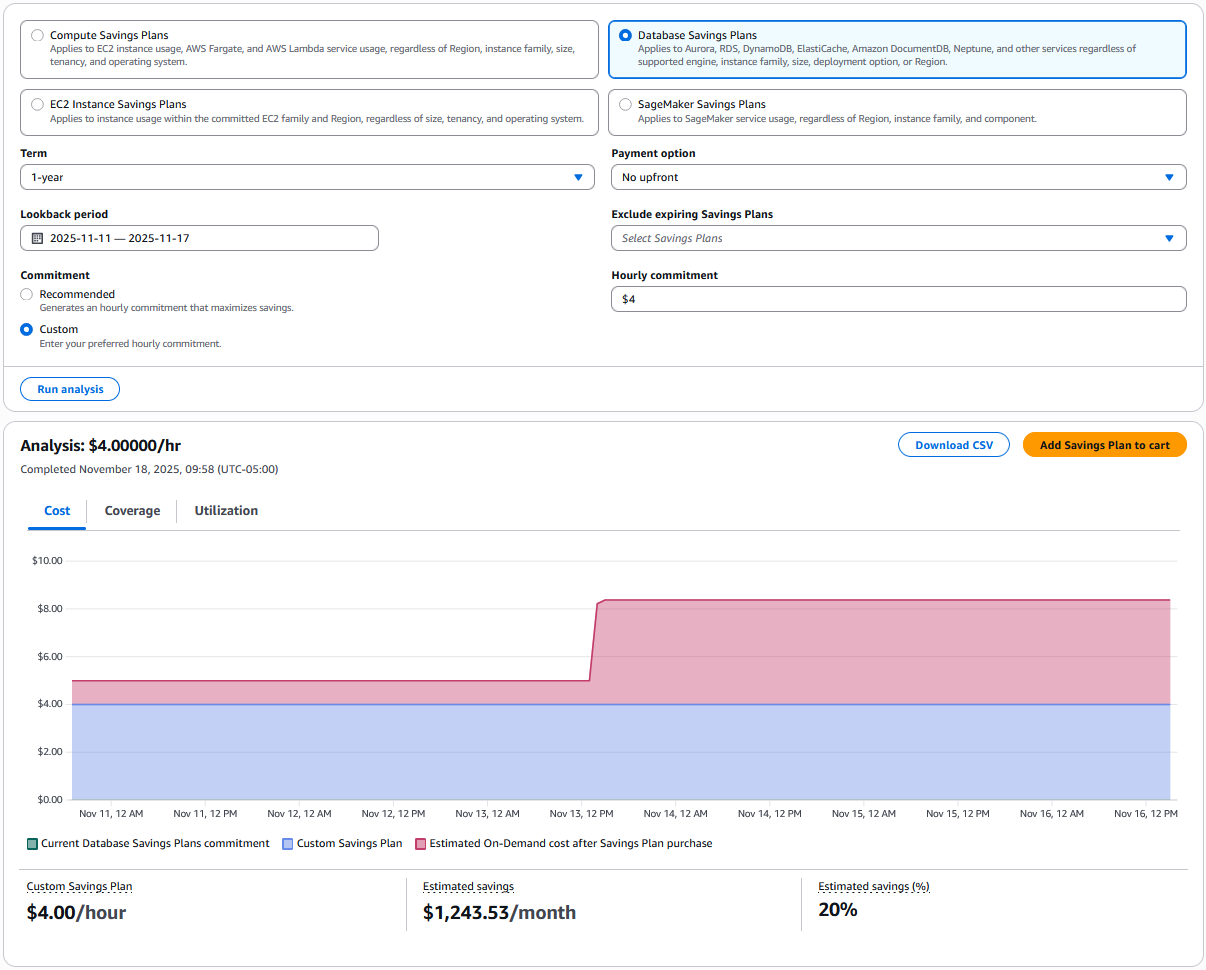
The Purchase Analyzer – is designed for modeling custom commitment levels. If you want to purchase a different amount than the recommended commitment on the Purchase Analyzer page, select Database Savings Plans and configure Lookback period and Hourly commitment to simulate alternative commitment levels and see the projected impact on Cost, Coverage, and Utilization.

This way is preferred if your purchasing strategy includes smaller, incremental commitments over time or if you expect future usage changes that could affect your ideal purchase amount.

After reviewing the recommendations or running simulations in Savings Plans Recommendations or Savings Plans Purchase Analyzer, choose Add to cart to proceed with your chosen commitment. If you prefer to purchase directly, you can also navigate to the Purchase Savings Plans page. The console updates estimated discounts and coverage in real time as you adjust each setting, so you can evaluate the impact before completing your order.

You can learn more about how to choose and purchase Database Saving Plans by visiting the Savings Plans User Guide documents.

Now available
Database Savings Plans are available in all AWS Regions outside of China. Give them a try and start shaping your database strategy with more flexibility and predictable costs.

– Betty

Amazon CloudWatch introduces unified data management and analytics for operations, security, and compliance

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-cloudwatch-introduces-unified-data-management-and-analytics-for-operations-security-and-compliance/

Today we’re expanding Amazon CloudWatch capabilities to unify and manage log data across operational, security, and compliance use cases with flexible and powerful analytics in one place and with reduced data duplication and costs.

This enhancement means that CloudWatch can automatically normalize and process data to offer consistency across sources with built-in support for Open Cybersecurity Schema Framework (OCSF) and Open Telemetry (OTel) formats, so you can focus on analytics and insights. CloudWatch also introduces Apache Iceberg compatible access to your data through Amazon Simple Storage Service (Amazon S3) Tables, so that you can run analytics, not only locally but also using Amazon Athena, Amazon SageMaker Unified Studio, or any other Iceberg-compatible tool.

You can also correlate your operational data in CloudWatch with other business data from your preferred tools to correlate with other data. This unified approach streamlines management and provides comprehensive correlation across security, operational, and business use cases.

Here are the detailed enhancements:

  • Streamline data ingestion and normalization – CloudWatch automatically collects AWS vended logs across accounts and AWS Regions, integrating with AWS Organizations from AWS services including AWS CloudTrail, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, AWS WAF access logs, Amazon Route 53 resolver logs, and pre-built connectors for third-party sources such as endpoint (CrowdStrike, SentinelOne), identity (Okta, Entra ID), cloud security (Wiz), network security (Zscaler, Palo Alto Networks), productivity and collaboration (Microsoft Office 365, Windows Event Logs, and GitHub), along with IT service manager with ServiceNow CMBD. To normalize and process your data as they are being ingested, CloudWatch offers managed OCSF conversion for various AWS and third-party data sources and other processors such ad Grok for custom parsing, field-level operations, and string manipulations.
  • Reduce costly log data management – CloudWatch consolidates log management into a single service with built-in governance capabilities without storing and maintaining multiple copies of the same data across different tools and data stores. The unified data store of CloudWatch eliminates the need for complex ETL pipelines and reduces your operational costs and management overhead needed to maintain multiple separate data stores and tools.
  • Discover business insights from log data – You can run queries in CloudWatch using natural language queries and popular query languages such as LogsQL, PPL, and SQL through a single interface, or query your data using your preferred analytics tools through Apache Iceberg-compatible tables. The new Facets interface gives you intuitive filtering by source, application, account, region, and log type, which you can use to run queries across log groups of multiple AWS accounts and Regions with intelligent parameter inference.

In the next sections we explore the new log management and analytics features of the CloudWatch Logs!

1. Data discovery and management by data sources and types

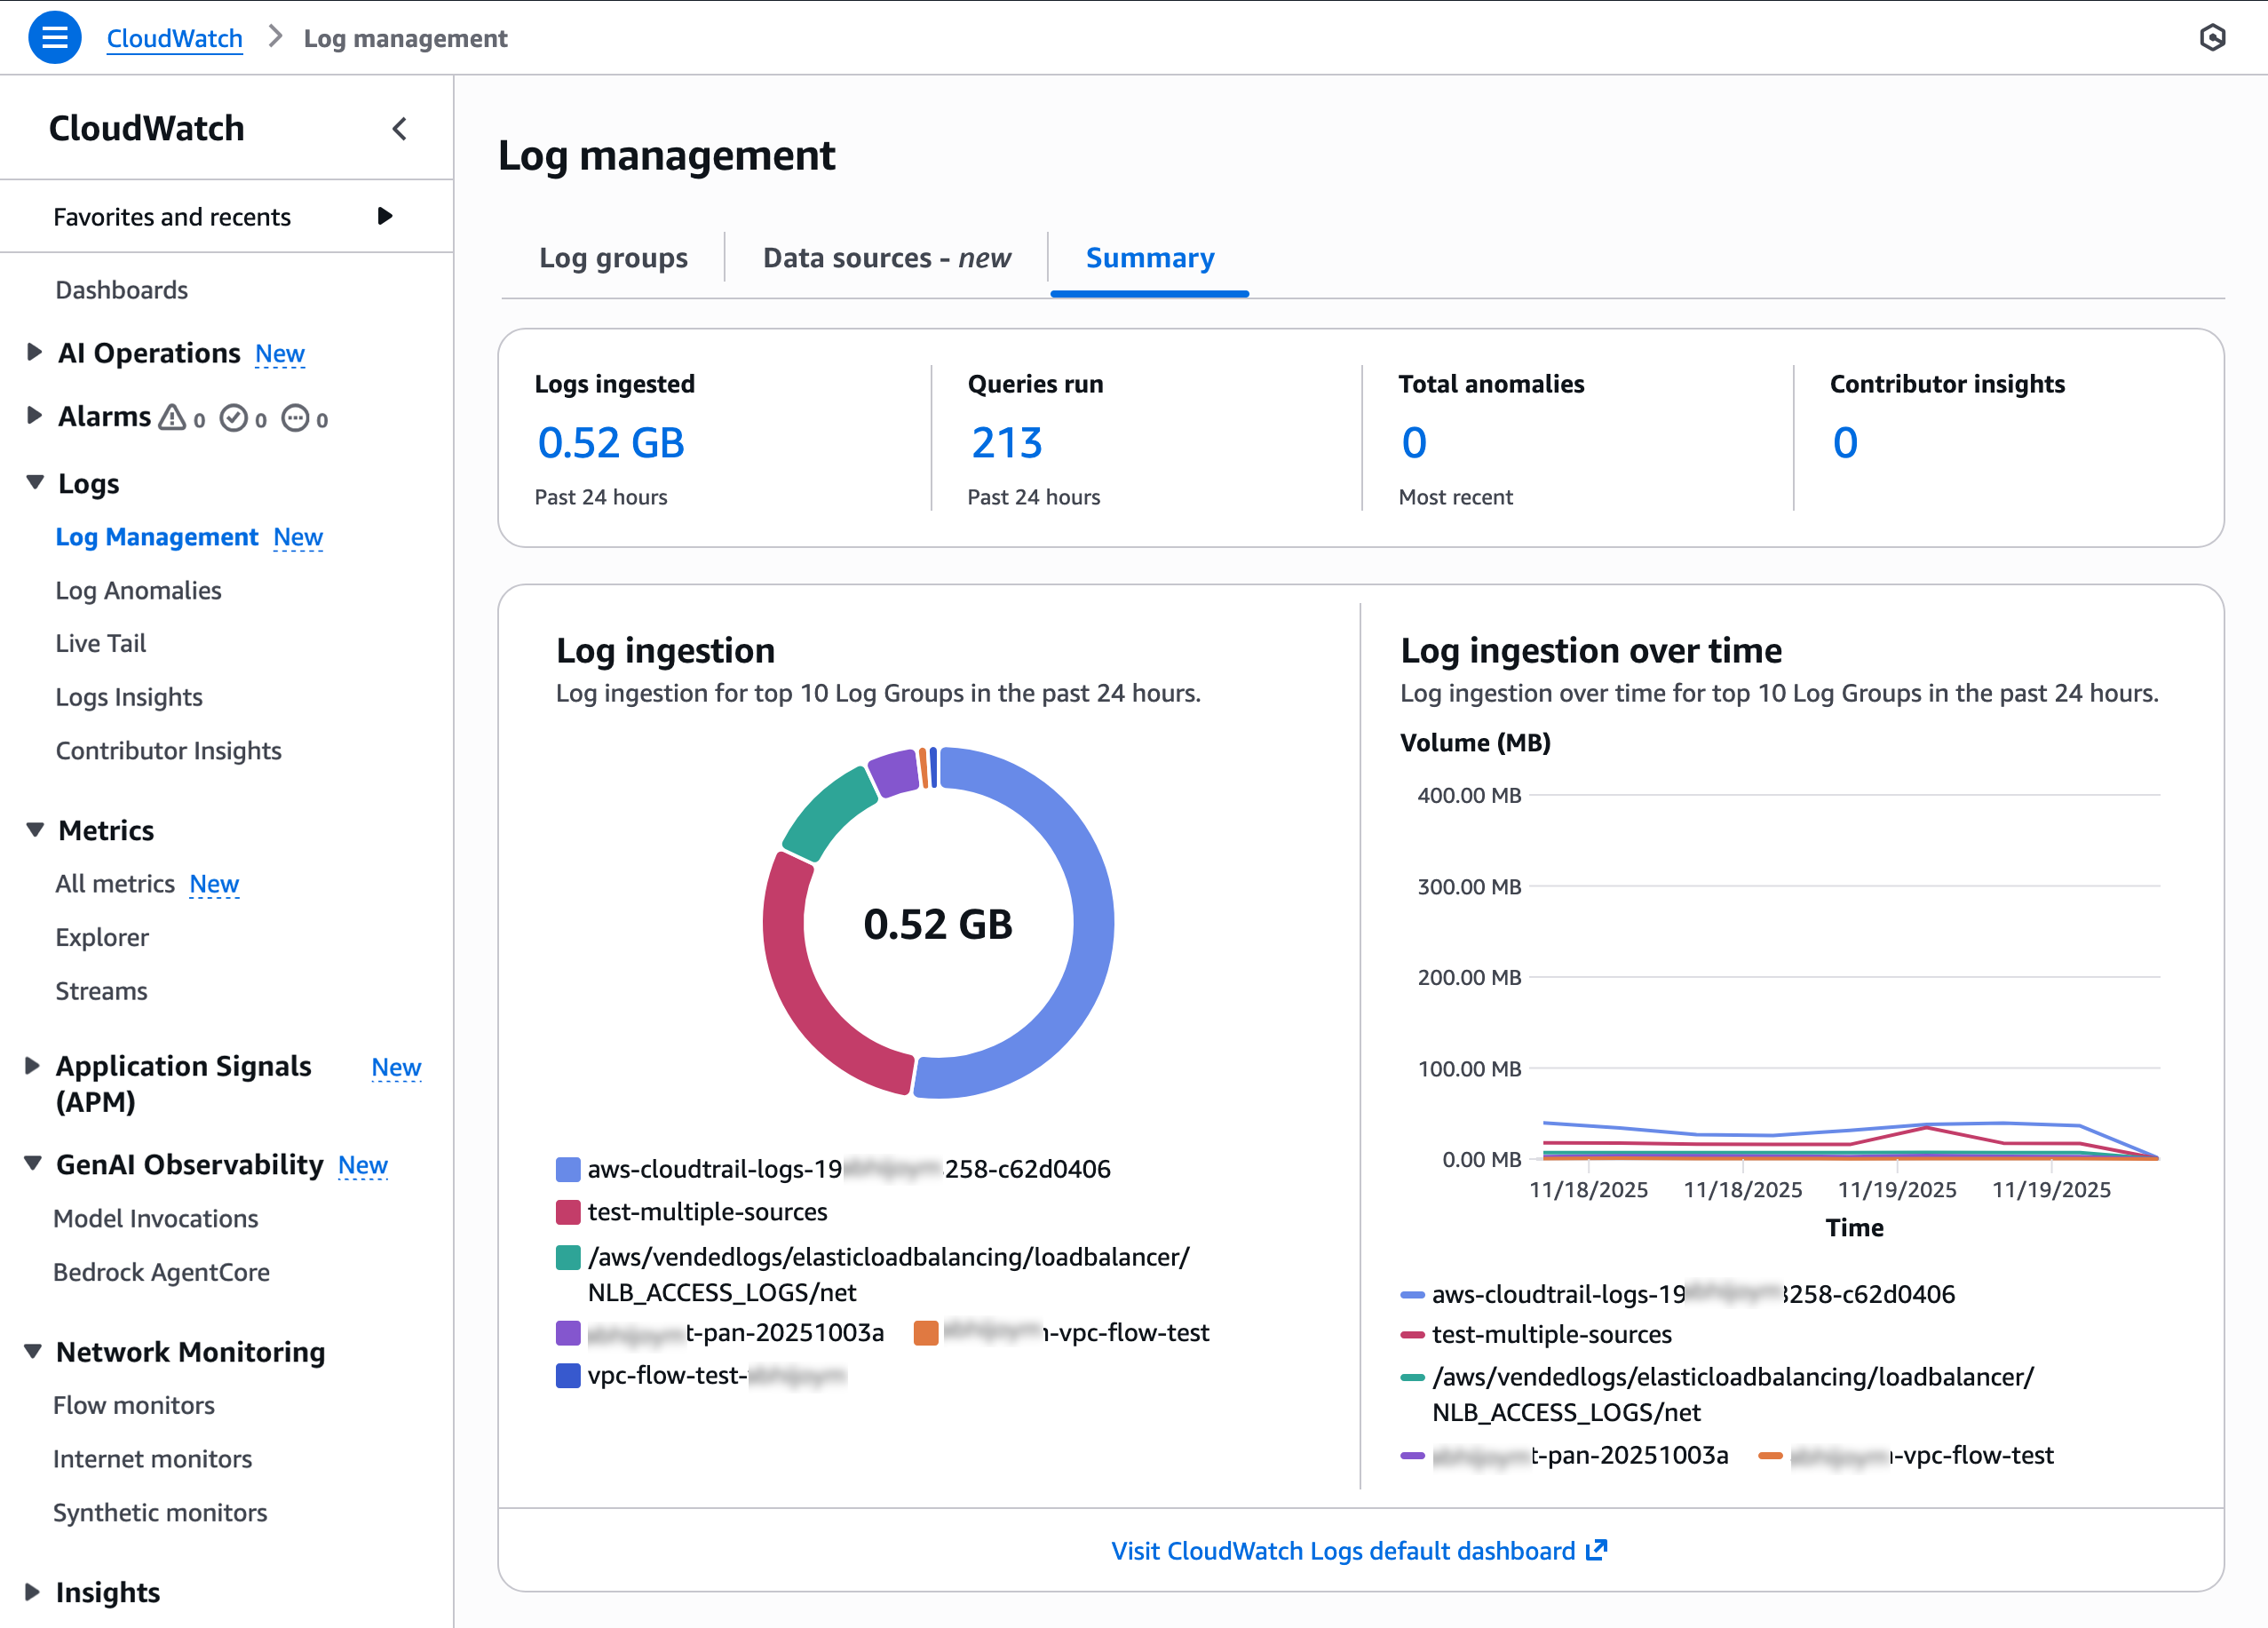
You can see a high-level overview of logs and all data sources with a new Logs Management View in the CloudWatch console. To get started, go to the CloudWatch console and choose Log Management under the Logs menu in the left navigation pane. In the Summary tab, you can observe your logs data sources and types, insights into how your log groups are doing across ingestion, and anomalies.

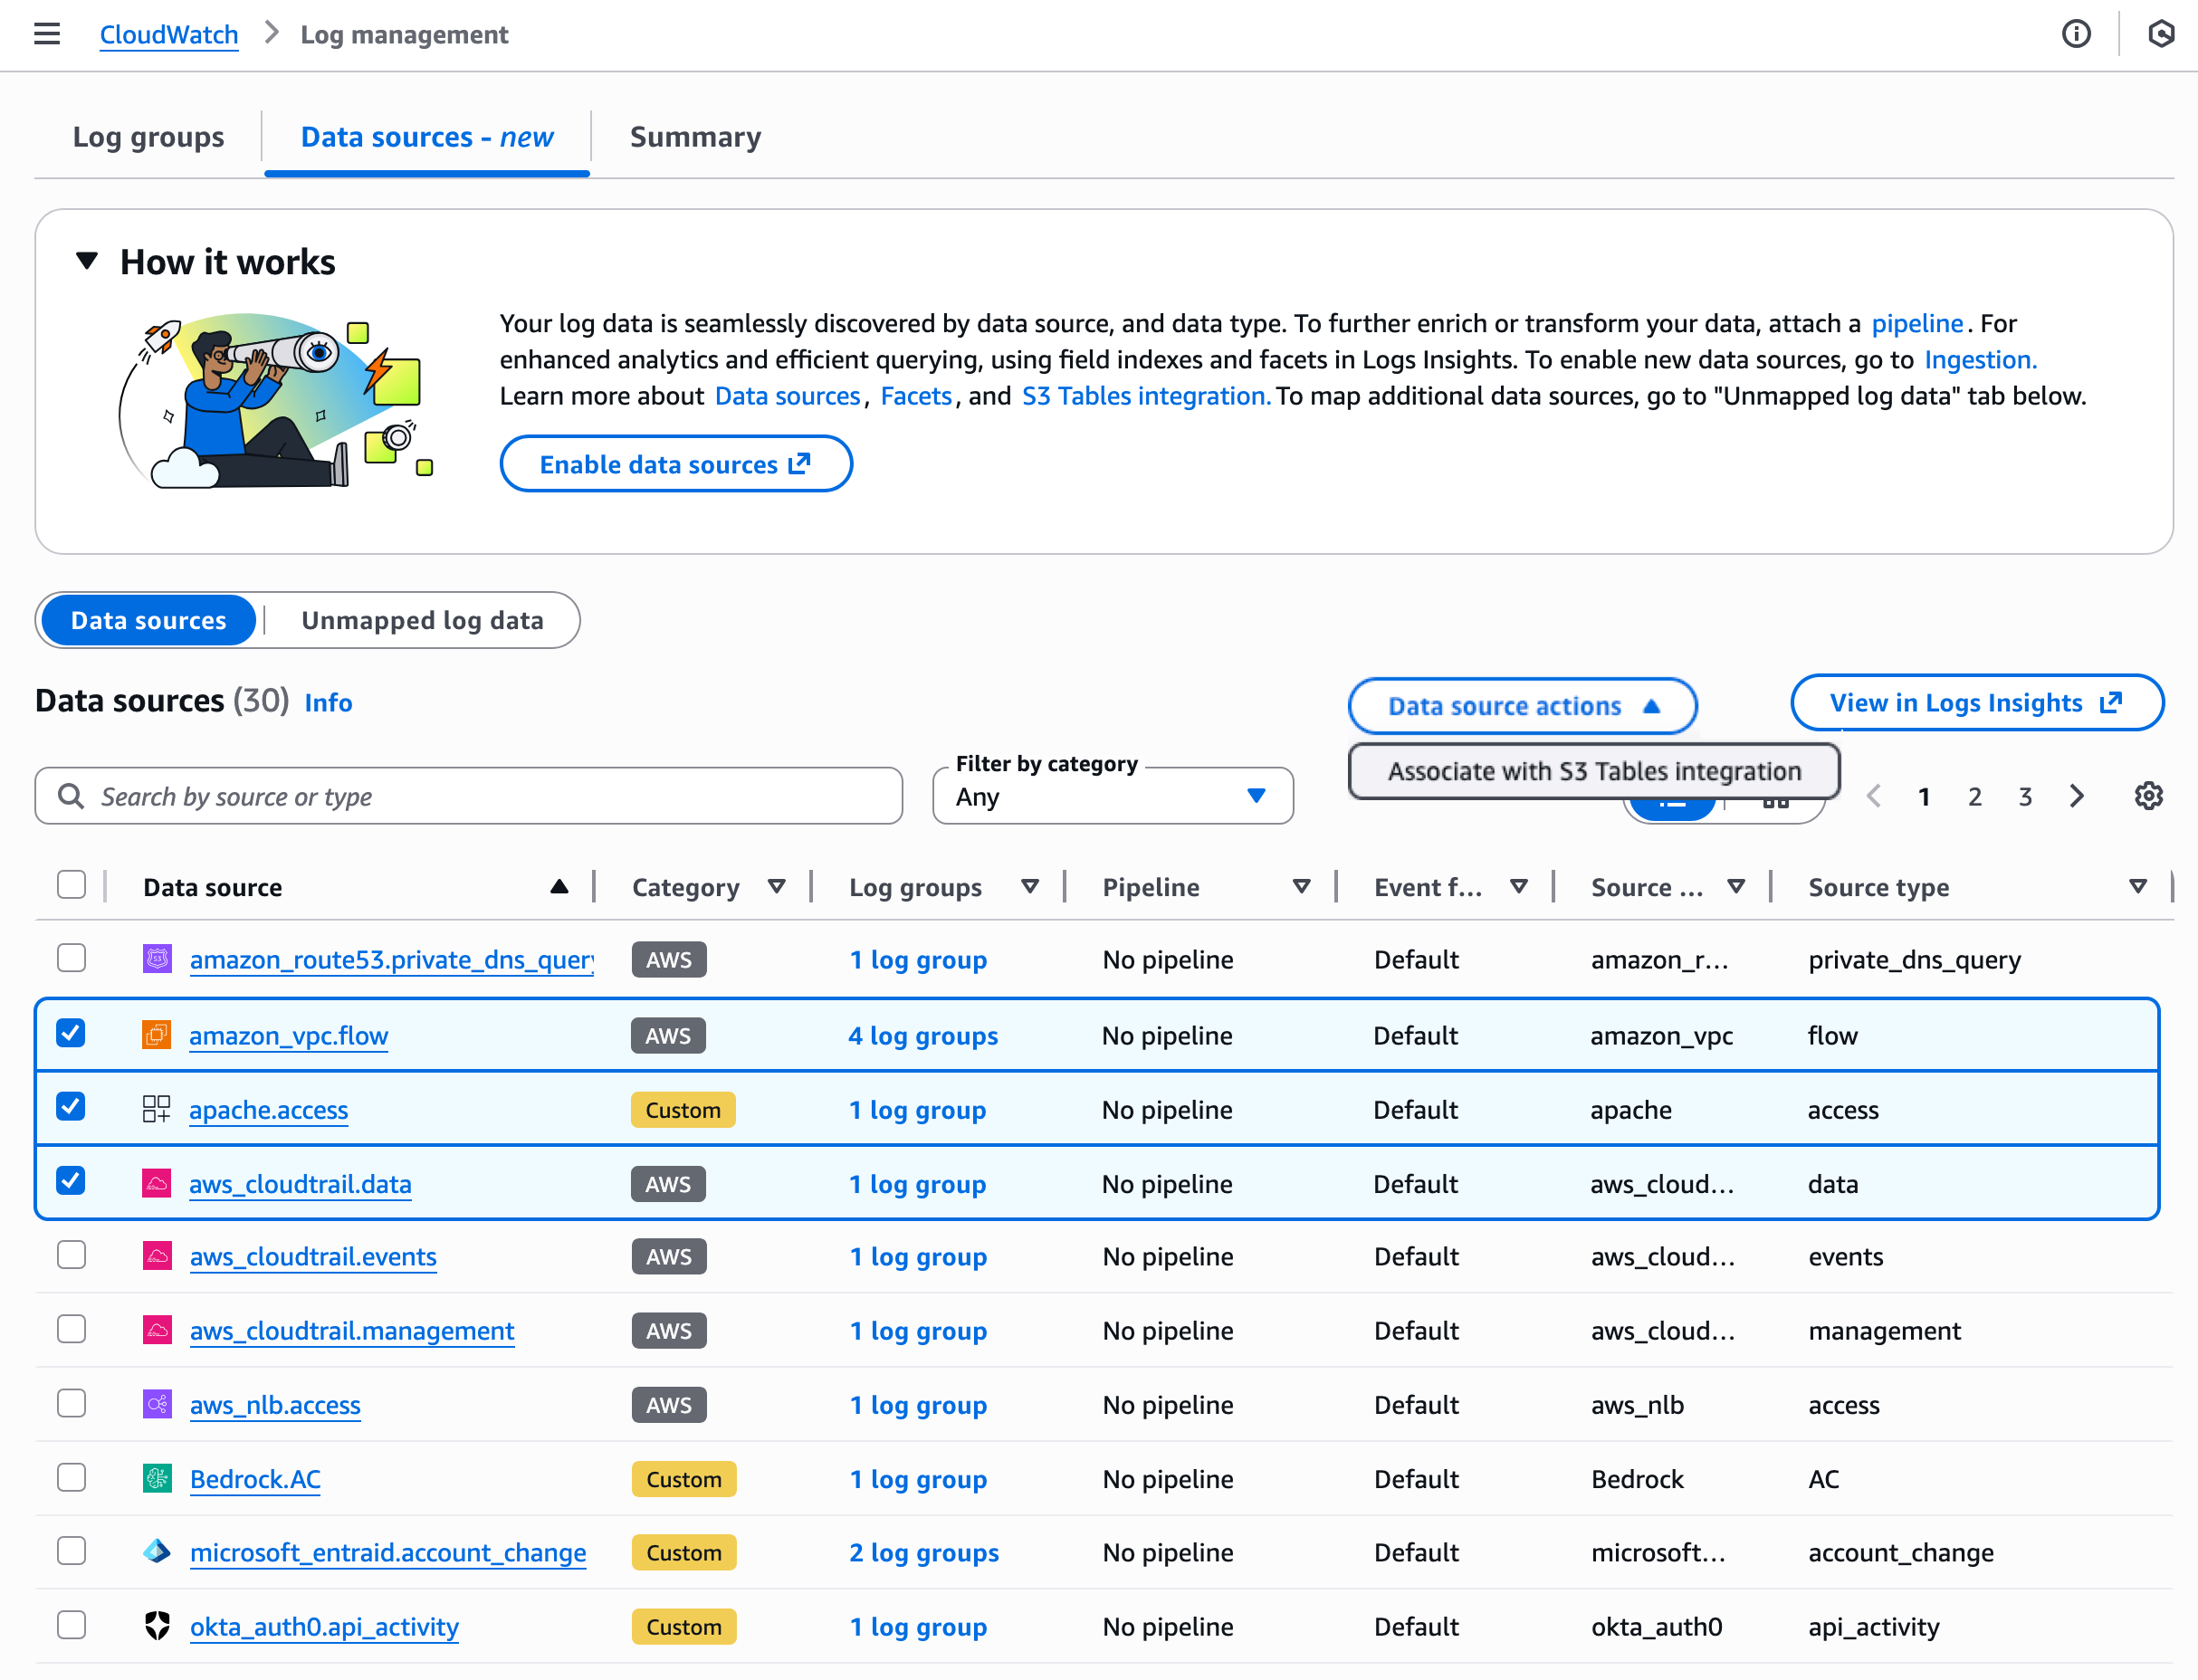
Choose the Data sources tab to find and manage your log data by data sources, types, and fields. CloudWatch ingests and automatically categorizes data sources by AWS services, third-party, or custom sources such as application logs.

Choose the Data source actions to integrate S3 Tables to make future logs for selected data sources. You have the flexibility to analyze the logs through Athena and Amazon Redshift and other query engines such as Spark using Iceberg compatible access patterns. With this integration, logs from CloudWatch are available in a read-only aws-cloudwatch S3 Tables bucket.

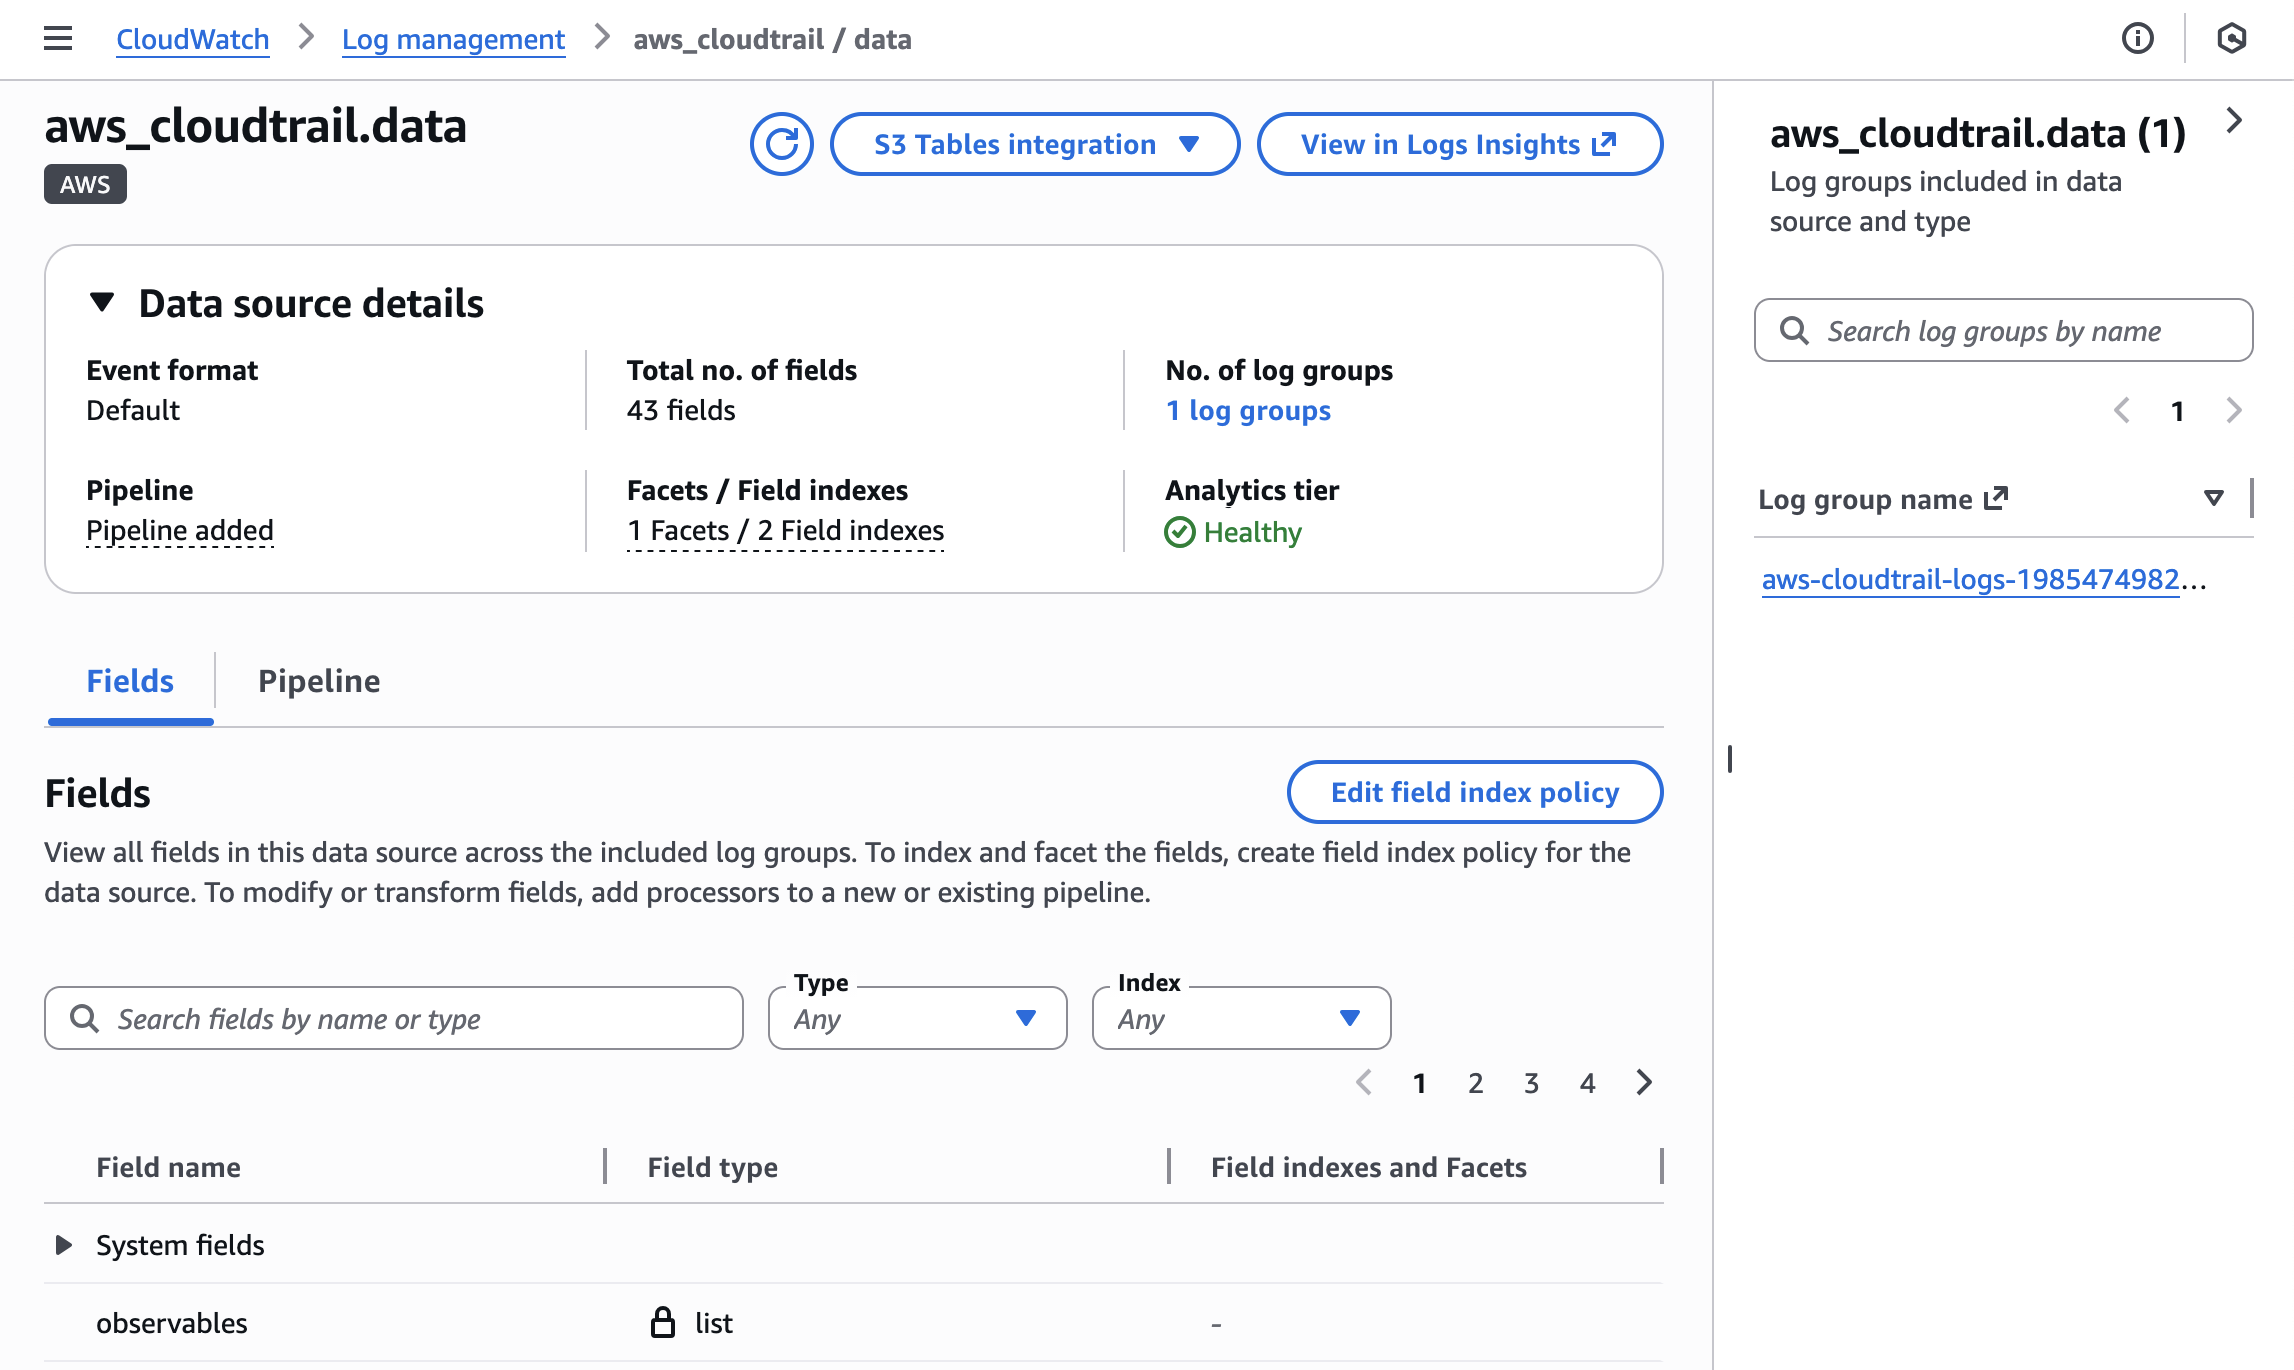
When you choose a specific data source such as CloudTrail data, you can view the details of the data source that includes information regarding data format, pipeline, facets/field indexes, S3 Tables association, and the number of logs with that data source. You can observe all log groups included in this data source and type and edit a source/type field index policy using the new schema support.

To learn more about how to manage your data sources and index policy, visit Data sources in the Amazon CloudWatch Logs User Guide.

2. Ingestion and transformation using CloudWatch pipelines

You can create pipelines to streamline collecting, transforming, and routing telemetry and security data while standardizing data formats to optimize observability and security data management. The new pipeline feature of CloudWatch connects data from a catalogue of data sources, so that you can add and configure pipeline processors from a library to parse, enrich, and standardize data.

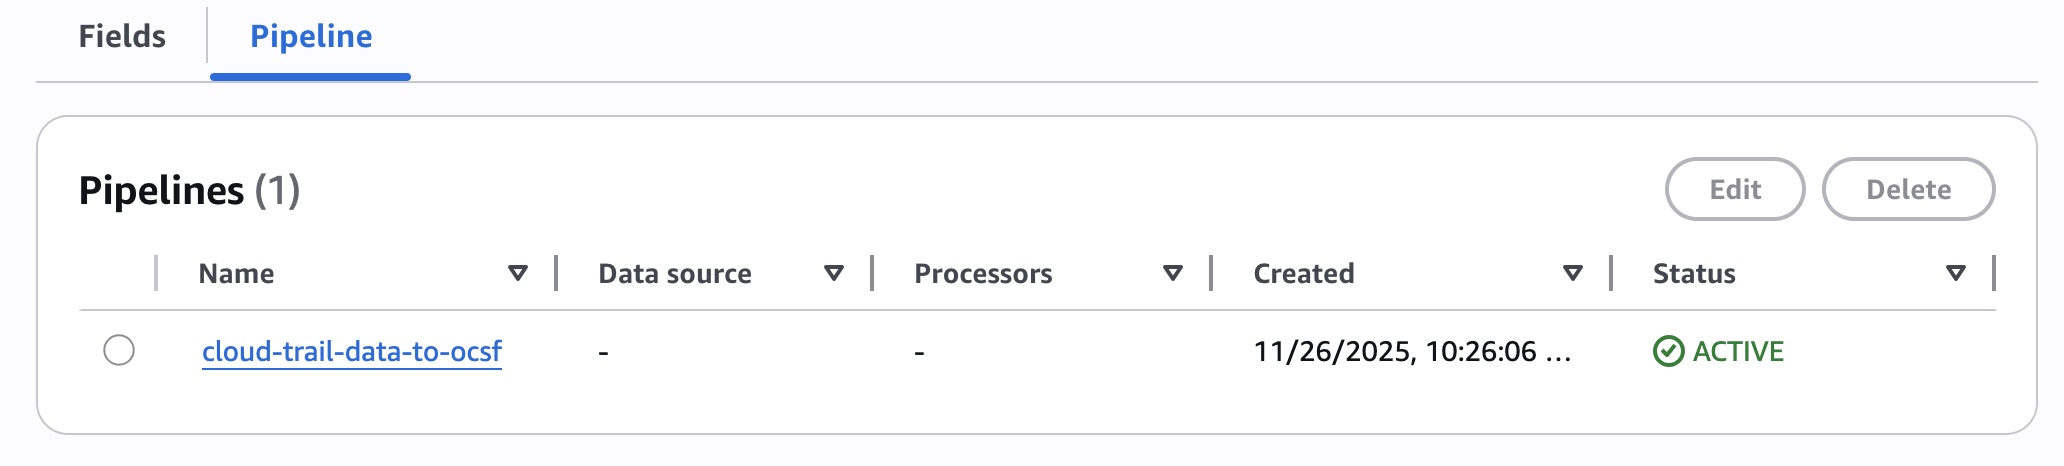
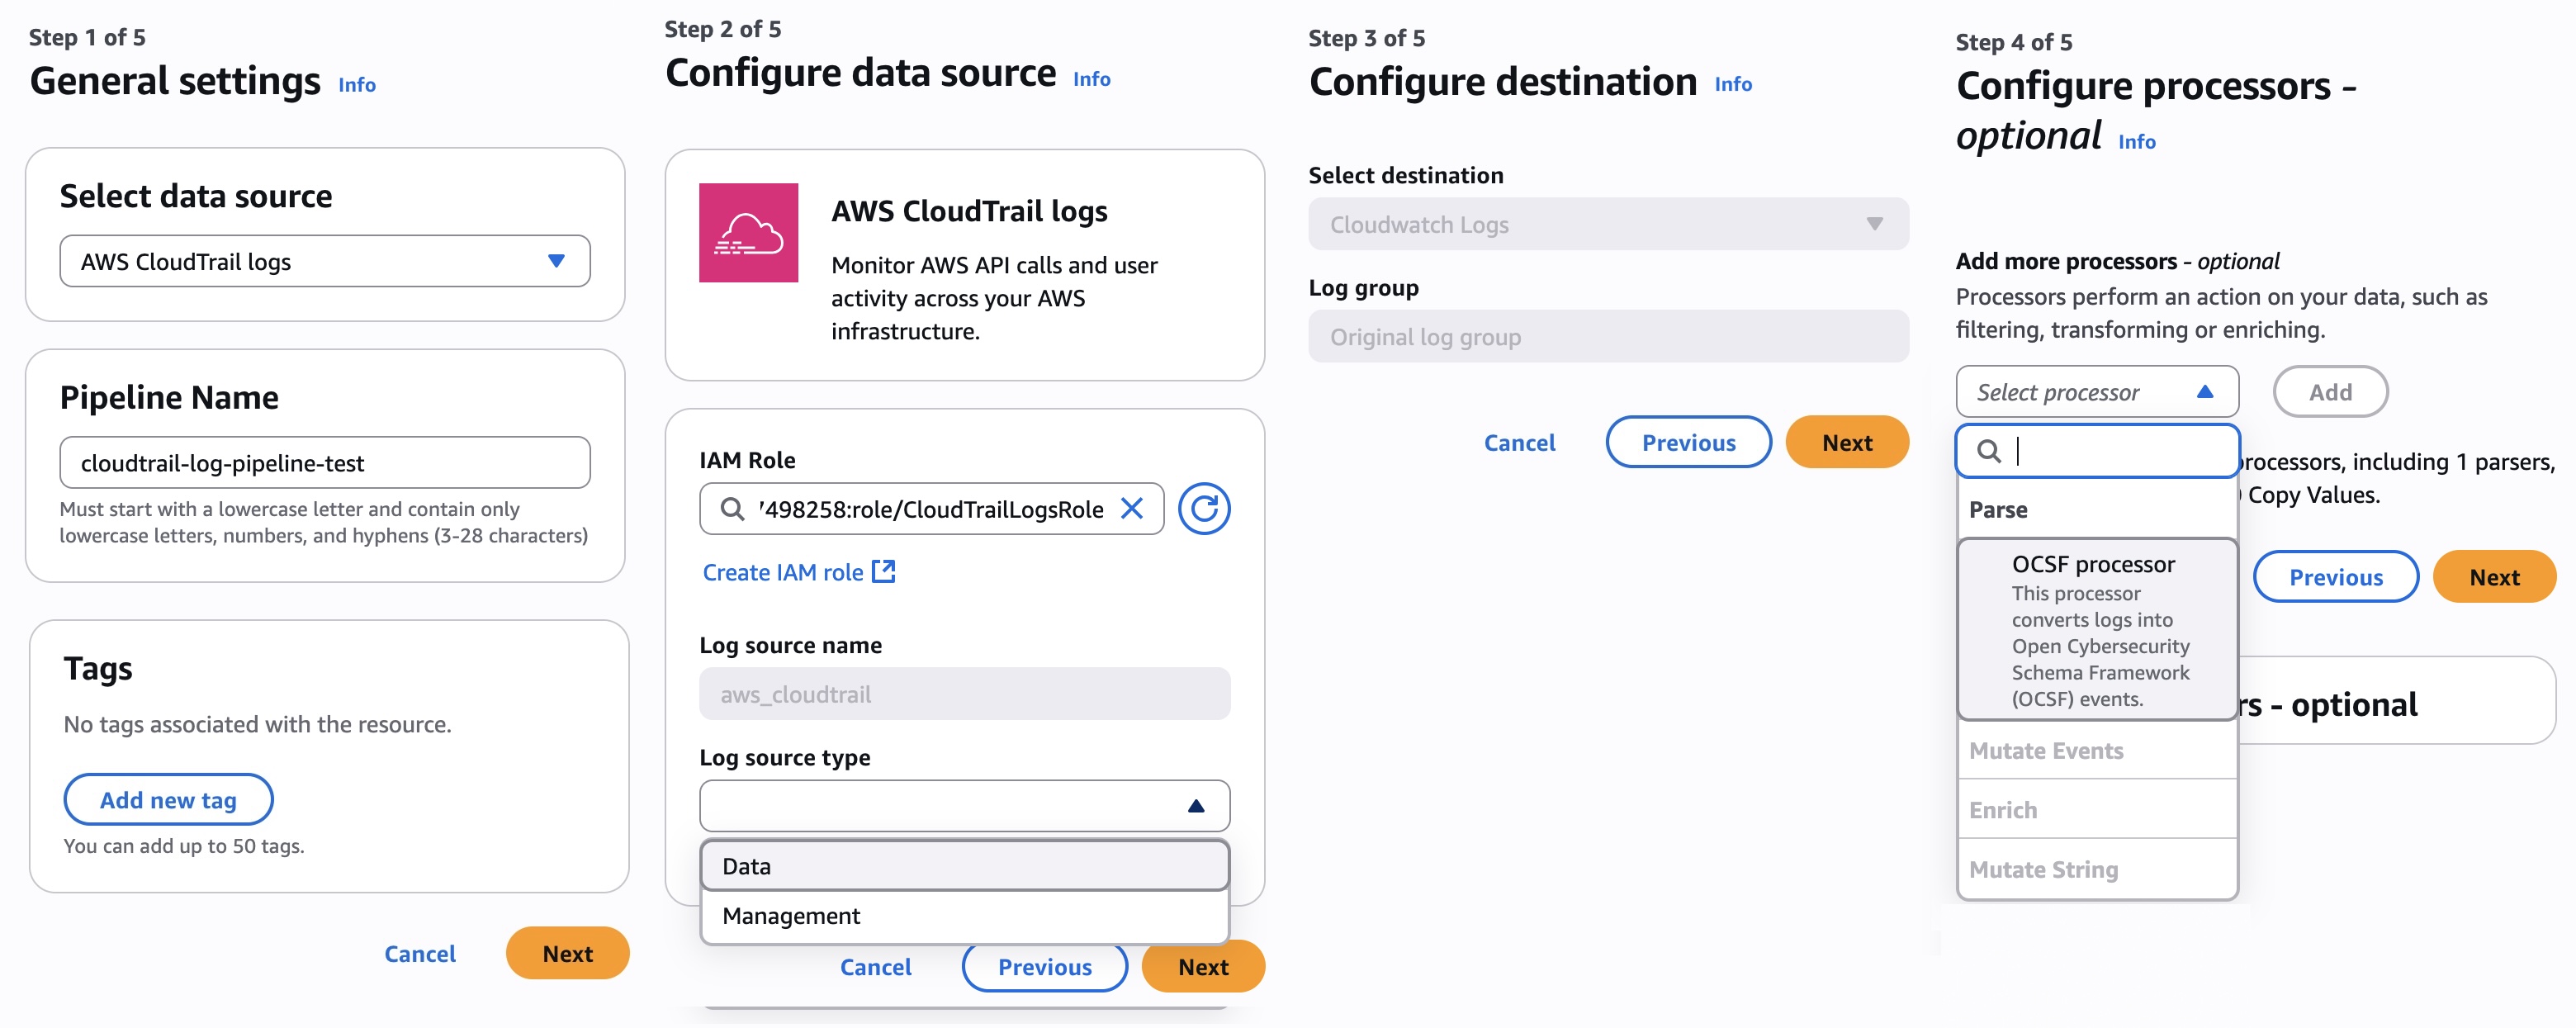
In the Pipeline tab, choose Add pipeline. It shows you the pipeline configuration wizard. This wizard guides you through five steps where you can choose the data source and other source details such as log source types, configure destination, configure up to 19 processors to perform an action on your data (such as filtering, transforming, or enriching), and finally review and deploy the pipeline.

You also have the option to create pipelines through the new Ingestion experience in CloudWatch. To learn more about how to set up and manage the pipelines, visit Pipelines in the Amazon CloudWatch Logs User Guide.

3. Enhanced analytics and querying based on data sources

You can enhance analytics with support for Facets and querying based on data sources. Facets enable interactive exploration and drill-down into logs and their values are automatically extracted based on the selected time period.

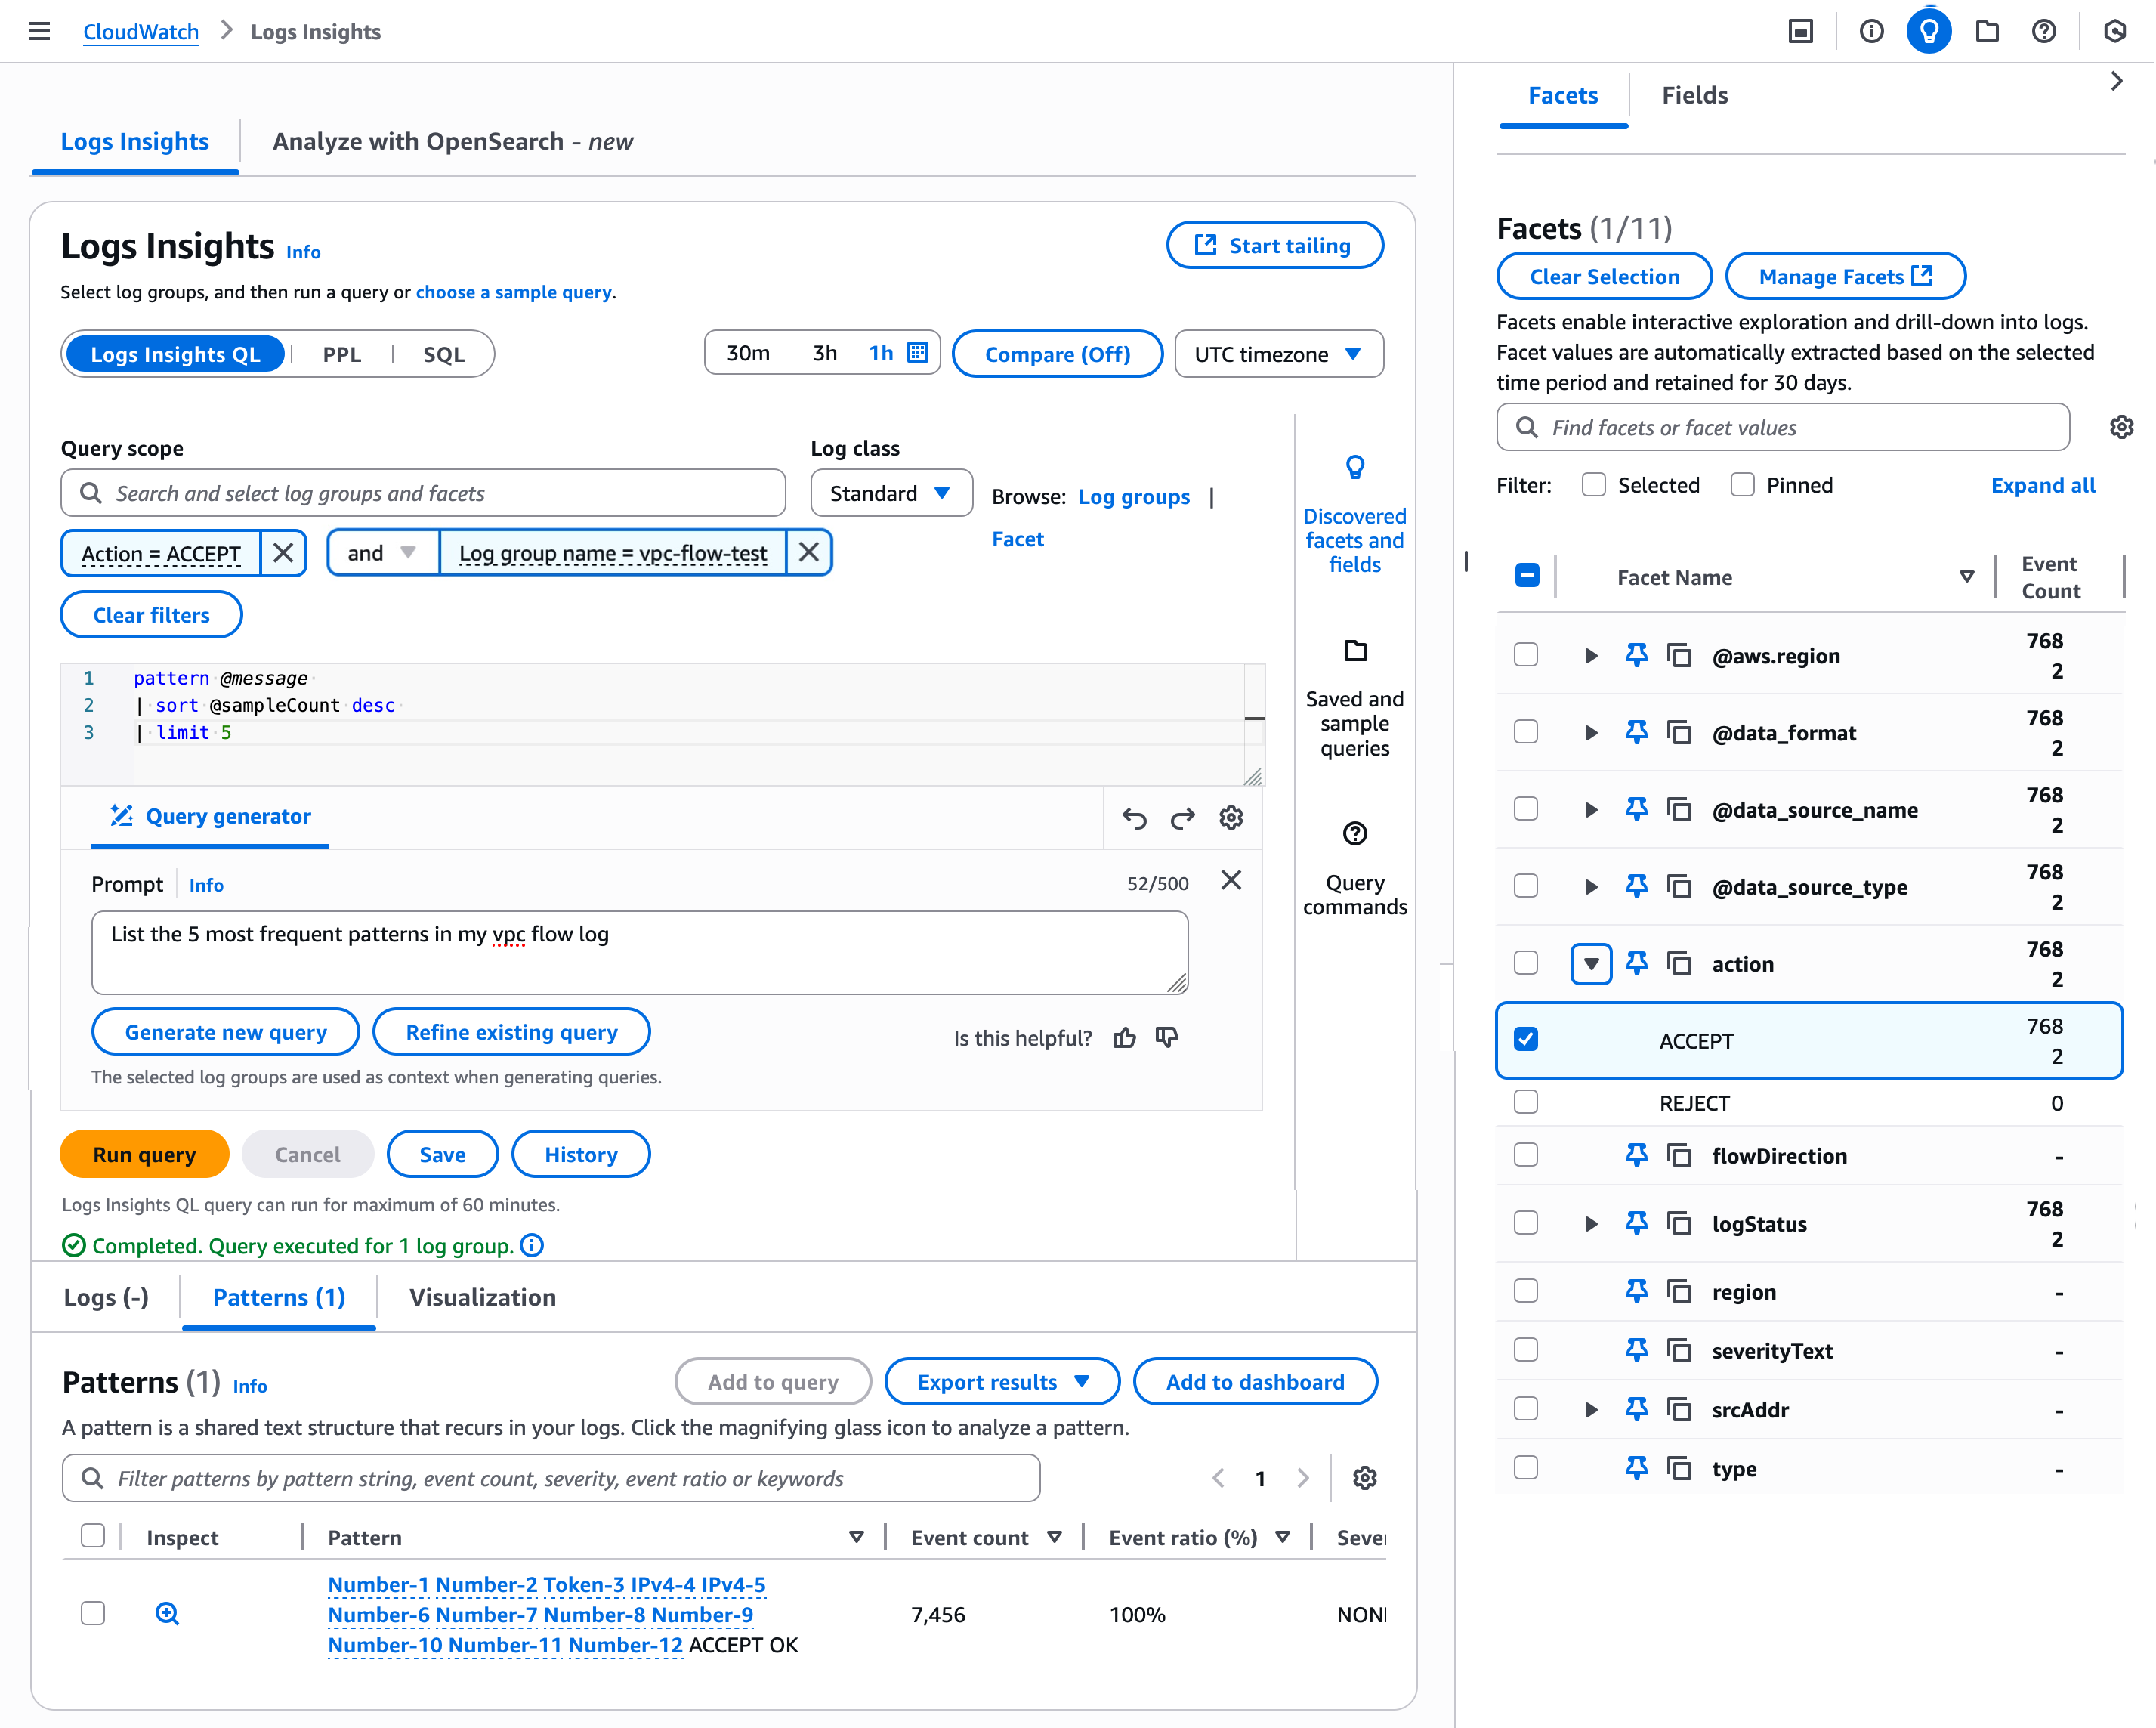
Choose the Facets tab in the Log Insights under the Logs menu in the left navigation pane. You can view available facets and values that appear in the panel. Choose one or more facets and values to interactively explore your data. I choose Facets regarding a VPC Flow Logs group and action, query to list the five most frequent patterns in my VPC Flow Logs through the AI query generator, and get the result patterns.

You can save your query with the selected Facets and values that you have specified. When you next choose your saved query, the logs to be queried have the pre-specified facets and values. To learn more about Facet management, visit Facets in the CloudWatch Logs User Guide.

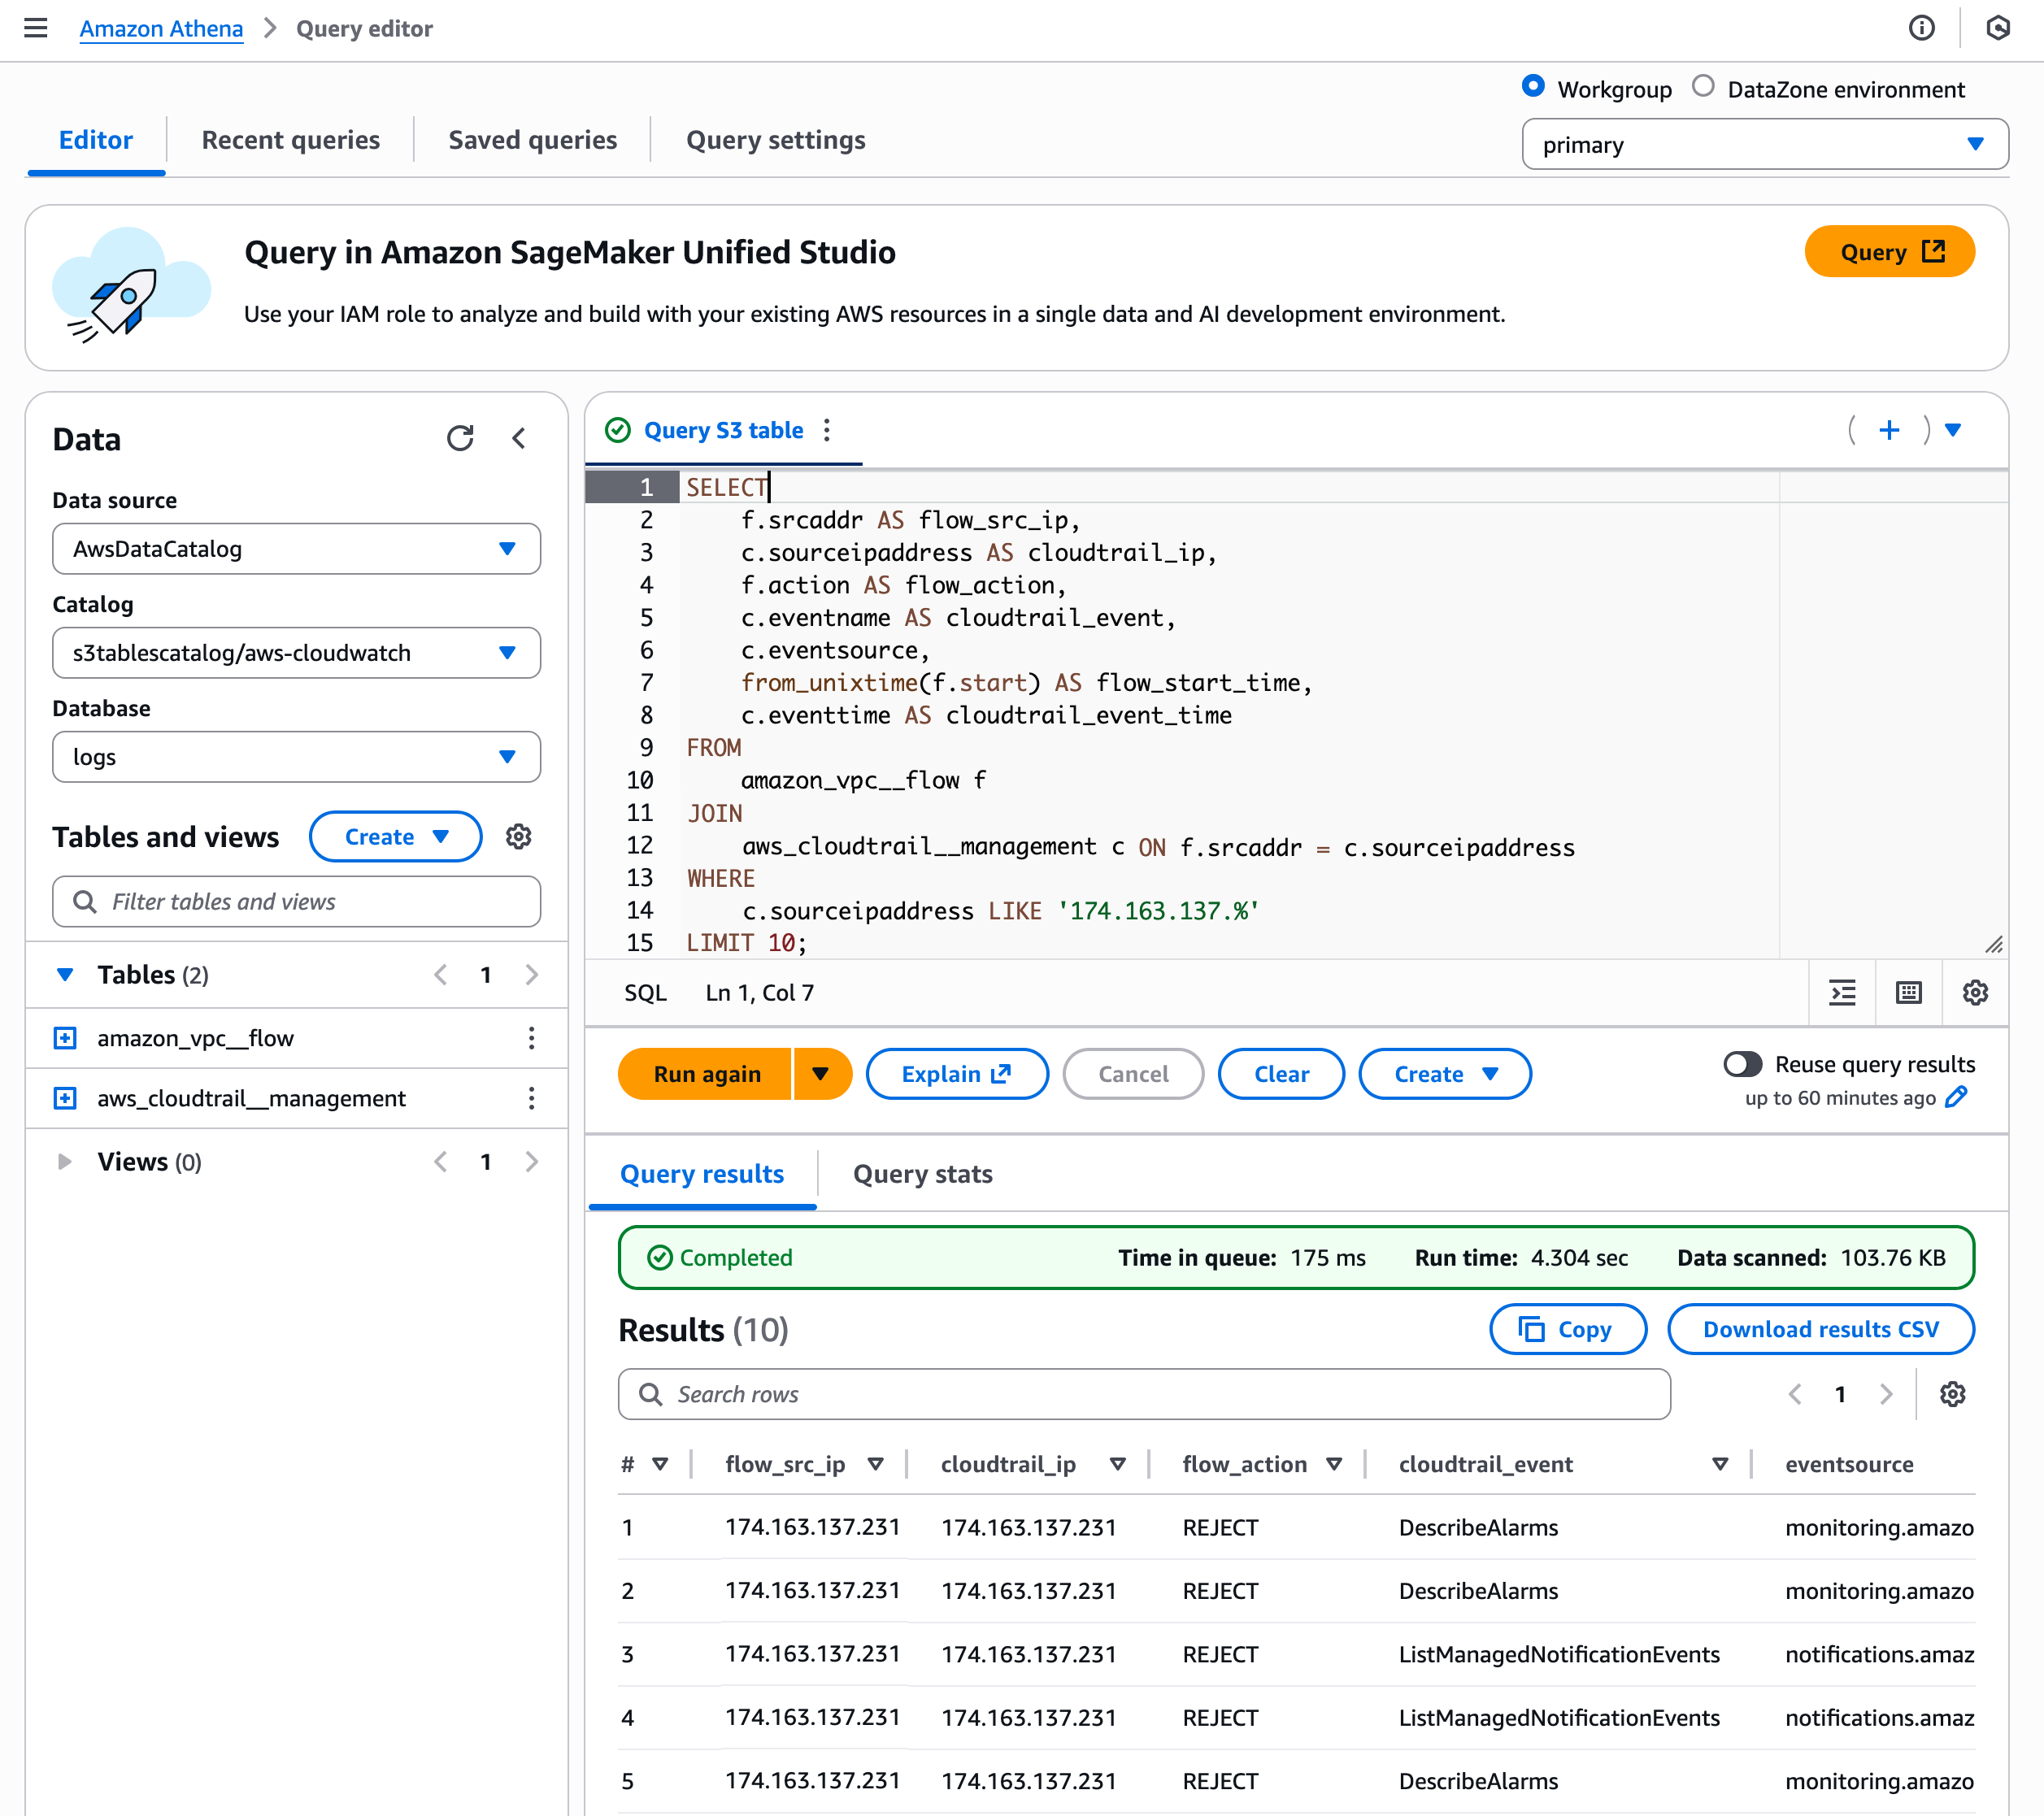
As I previously noted, you can integrate data sources into S3 Tables and query together. For example, using a Query Editor in Athena, you can query correlates network traffic with AWS API activity from a specific IP range (174.163.137.*) by joining VPC Flow Logs with CloudTrail logs based on matching source IP addresses.

This type of integrated search is particularly valuable for security monitoring, incident investigation, and suspicious behavior detection. You can view if an IP that’s making network connections is also performing sensitive AWS operations such as creating users, modifying security groups, or accessing data.

To learn more, visit S3 Tables integration with CloudWatch in the CloudWatch Logs User Guide.

Now available
New log management features of Amazon CloudWatch are available today in all AWS Regions except the AWS GovCloud (US) Regions and China Regions. For Regional availability and future roadmap, visit the AWS Capabilities by Region. There are no upfront commitments or minimum fees, and you pay for the usage of existing CloudWatch Logs for data ingestion, storage, and queries. To learn more, visit the CloudWatch pricing page.

Give it a try in the CloudWatch console. To learn more, visit the CloudWatch product page and send feedback to AWS re:Post for CloudWatch Logs or through your usual AWS Support contacts.

— Channy

New and enhanced AWS Support plans add AI capabilities to expert guidance

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/new-and-enhanced-aws-support-plans-add-ai-capabilities-to-expert-guidance/

Today, we’re announcing a fundamental shift in how AWS Support helps customers move from reactive problem-solving to proactive issue prevention. This evolution introduces new Support plans that combine AI-powered capabilities with Amazon Web Services (AWS) expertise. The new and enhanced plans help you identify and address potential issues before they impact your business operations, helping you to operate and optimize your cloud workloads more effectively.

The portfolio includes three plans designed to match different operational needs. Each plan offers distinct capabilities, with higher tiers including all the capabilities of lower tiers plus additional features and enhanced service levels. Let’s have a look at them.

New and enhanced AWS Support paid plans
Business Support+ transforms the developer, startup, and small business experience by providing intelligent assistance powered by AI. You can choose to engage directly with AWS experts or start with AI-powered contextual recommendations that seamlessly transition to AWS experts when needed. AWS experts respond in within 30 minutes for critical cases(twice as fast as before), maintaining previous context and saving you from having to repeat yourself.

With a low-cost monthly subscription, this plan delivers advanced operational capabilities through a combination of AI-powered tools and AWS expertise. The plan provides personalized recommendations to help optimize your workloads based on your specific environment, while maintaining seamless access to AWS experts for technical support when needed.

Enterprise Support builds on our established support model, this tier accelerates innovation and cloud operations success through intelligent operations and AI-powered trusted human guidance. Your designated technical account manager (TAM) combines deep AWS knowledge with data-driven insights from your environment to help identify optimization opportunities and potential risks before they impact your operations. The plan also offers access to AWS Security Incident Response at no additional fee, a comprehensive service that centralizes tracking, storage, and management of security events while providing automated monitoring and investigation capabilities to strengthen your security posture.

Through AI-powered assistance and continuous monitoring of your AWS environment, this tier helps you achieve new levels of scale in your operations. With up to 15-minute response times for production-critical issues and support engineers who receive personalized context delivered by AI agents, this tier enables faster and more personalized resolution while maintaining operational excellence. Additionally, you also get access to interactive programs and hands-on workshops to foster continuous technical growth.

Unified Operations Support delivers our highest level of context-aware Support through an expanded team of AWS experts. Your core team comprised of a Technical Account Manager, a Domain Engineer, and a designated Senior Billing and Account Specialist is complemented by on-demand experts in migration, incident management, and security. These designated experts understand your unique environment and operational history, providing guidance through your preferred collaboration channels while combining their architectural knowledge with AI-powered insights.

Through comprehensive around-the-clock monitoring and AI-powered automation, this tier strengthens your mission-critical operations with proactive risk identification and contextual guidance. When critical incidents occur, you receive 5-minute response times with technical recommendations provided by Support engineers who understand your workloads. The team conducts systematic application reviews, helps validate operational readiness, and supports business-critical events, which means you can focus on innovation while maintaining the highest levels of operational excellence.

Transforming your cloud operations
AWS Support is evolving to help you build, operate, and optimize your cloud infrastructure more effectively. We maintain context of your account’s support history and previous cases, configuration, and previous cases, so our AI-powered capabilities and AWS experts can deliver more relevant and effective solutions tailored to your specific environment.

Support plan capabilities will continuously evolve to add comprehensive visibility into your infrastructure, delivering actionable insights across performance, security, and cost dimensions with clear evaluation of business impact and cost benefits. This combination of AI-powered tools and AWS expertise represents a fundamental shift from reactive to proactive operations, helping you prevent issues before they impact your business.

Subscribers of AWS Developer Support, AWS Business Support (classic), and AWS Enterprise On-Ramp Support plans can continue to receive their current level of support through January 1, 2027. You can transition to one of the new and enhanced plans at any time before then by visiting the AWS Management Console or by reaching out to your AWS account team. Customers subscribed to AWS Enterprise Support can begin using the new features of this plan at any time.

Things to know
Business Support+, Enterprise Support, and Unified Operations are available in all commercial AWS Regions. Existing customers can continue their current plans or explore the new offerings for enhanced performance and efficiency.

Business Support+ starts at $29 per month, a 71% savings over the previous Business Support monthly minimum. Enterprise Support starts at $5,000 per month, a 67% savings over the previous Enterprise Support minimum price. Unified Operations, designed for organizations with mission-critical workloads and including a designated team of AWS experts, starts at $50,000 a month. All new Support plans use pricing tiers, which rewards higher usage with lower marginal prices for Support.

For critical cases, AWS Support provides different target response times across the plans. Business Support+ offers a 30-minute response time, Enterprise Support responds within 15 minutes, and Unified Operations Support delivers the fastest response time at 5 minutes.

To learn more about AWS Support plans and features, visit the AWS Support page or sign in to the AWS Management Console.

For hands-on guidance with AWS Support features, schedule a consultation with your account team.

Amazon OpenSearch Service improves vector database performance and cost with GPU acceleration and auto-optimization

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-opensearch-service-improves-vector-database-performance-and-cost-with-gpu-acceleration-and-auto-optimization/

Today we’re announcing serverless GPU acceleration and auto-optimization for vector index in Amazon OpenSearch Service that helps you build large-scale vector databases faster with lower costs and automatically optimize vector indexes for optimal trade-offs between search quality, speed, and cost.

Here are the new capabilities introduced today:

  • GPU acceleration – You can build vector databases up to 10 times faster at a quarter of the indexing cost when compared to non-GPU acceleration, and you can create billion-scale vector databases in under an hour. With significant gains in cost saving and speed, you get an advantage in time-to-market, innovation velocity, and adoption of vector search at scale.
  • Auto-optimization – You can find the best balance between search latency, quality, and memory requirements for your vector field without needing vector expertise. This optimization helps you achieve better cost-savings and recall rates when compared to default index configurations, while manual index tuning can take weeks to complete.

You can use these capabilities to build vector databases faster and more cost-effectively on OpenSearch Service. You can use them to power generative AI applications, search product catalogs and knowledge bases, and more. You can enable GPU acceleration and auto-optimization when you create a new OpenSearch domain or collection, as well as update an existing domain or collection.

Let’s go through how it works!

GPU acceleration for vector index
When you enable GPU acceleration on your OpenSearch Service domain or Serverless collection, OpenSearch Service automatically detects opportunities to accelerate your vector indexing workloads. This acceleration helps build the vector data structures in your OpenSearch Service domain or Serverless collection.

You don’t need to provision the GPU instances, manage their usage or pay for idle time. OpenSearch Service securely isolates your accelerated workloads to your domain’s or collection’s Amazon Virtual Private Cloud (Amazon VPC) within your account. You pay only for useful processing through the OpenSearch Compute Units (OCU) – Vector Acceleration pricing.

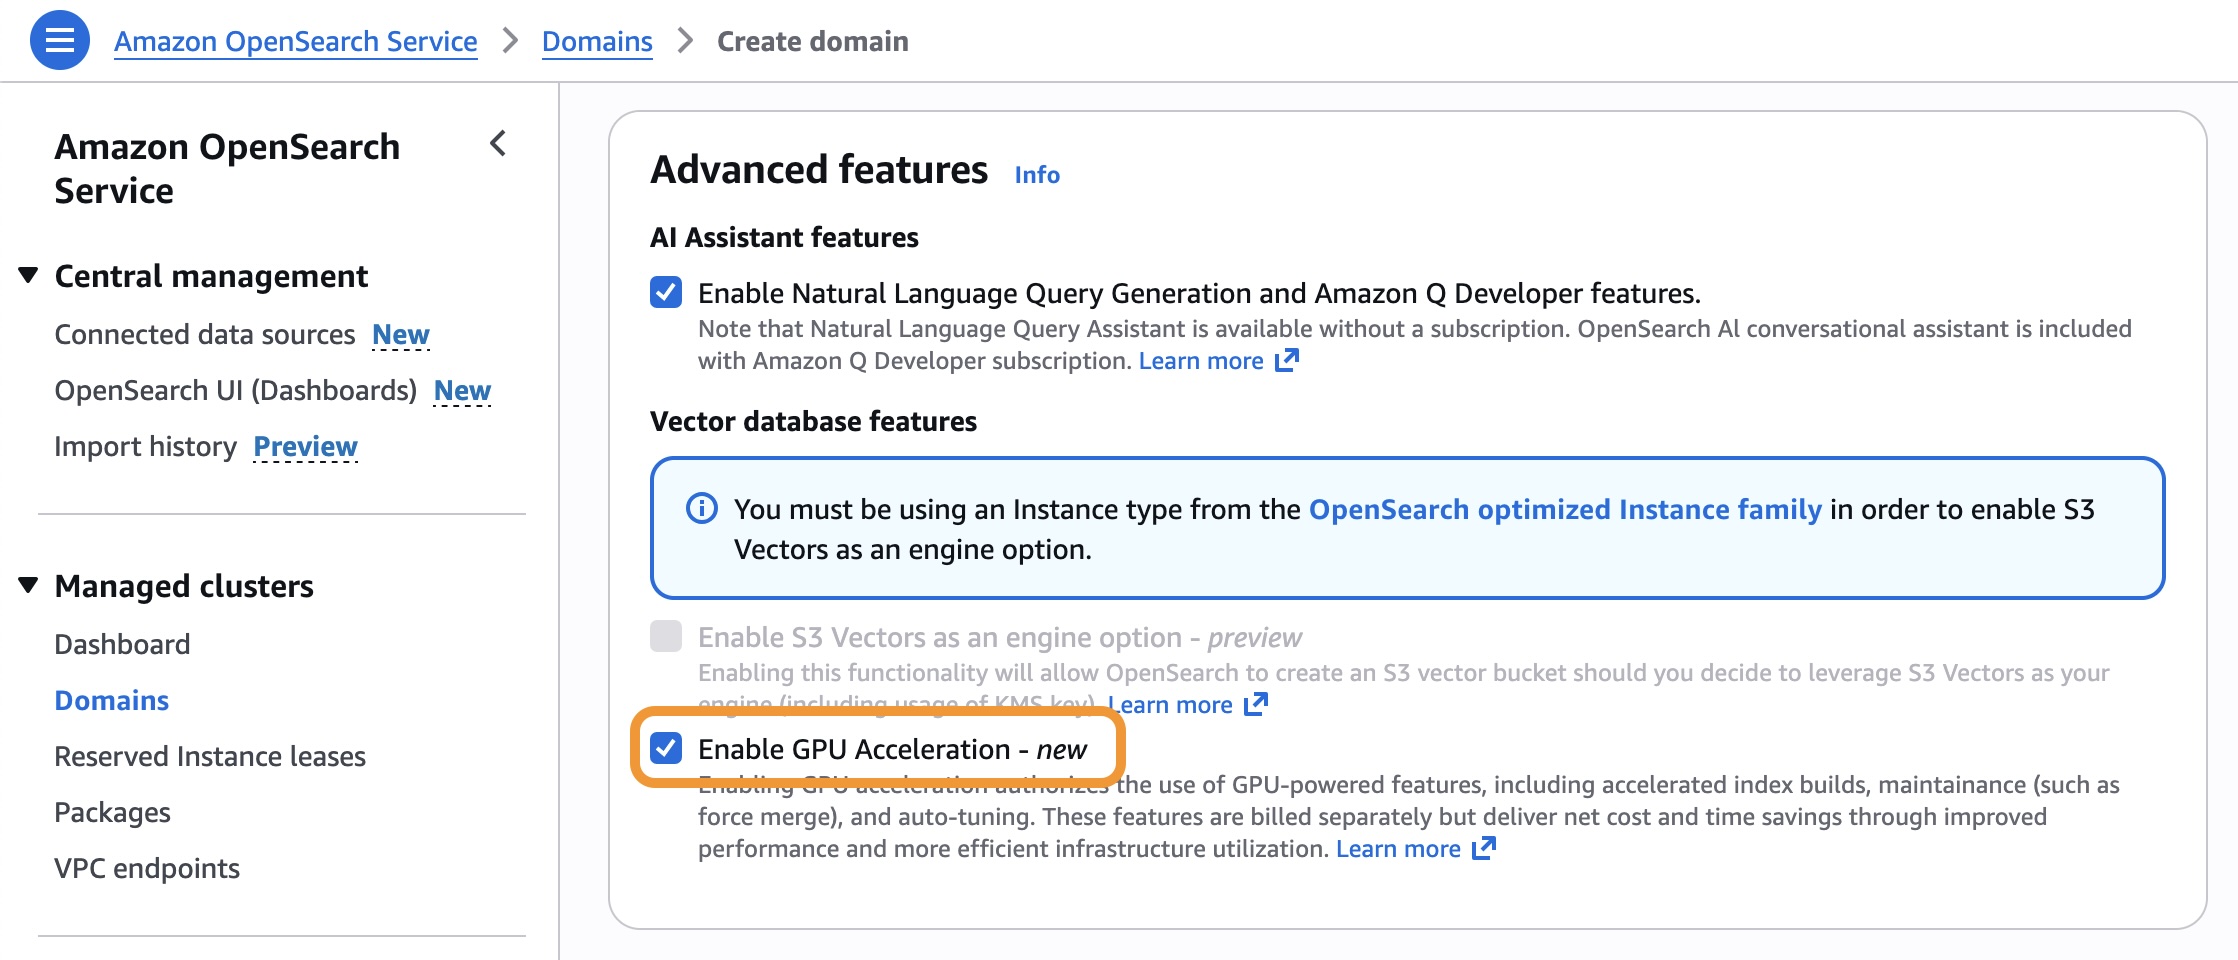
To enable GPU acceleration, go to the OpenSearch Service console and choose Enable GPU Acceleration in the Advanced features section when you create or update your OpenSearch Service domain or Serverless collection.

You can use the following AWS Command Line Interface (AWS CLI) command to enable GPU acceleration for an existing OpenSearch Service domain.

$ aws opensearch update-domain-config \
    --domain-name my-domain \
    --aiml-options '{"ServerlessVectorAcceleration": {"Enabled": true}}'

You can create a vector index optimized for GPU processing. This example index stores 768-dimensional vectors for text embeddings by enabling index.knn.remote_index_build.enabled.

PUT my-vector-index
{
    "settings": {
        "index.knn": true,
        "index.knn.remote_index_build.enabled": true
    },
    "mappings": {
        "properties": {
        "vector_field": {
        "type": "knn_vector",
        "dimension": 768,
      },
      "text": {
        "type": "text"
      }
    }
  }
}

Now you can add vector data and optimize your index using standard OpenSearch Service operations using the bulk API. The GPU acceleration is automatically applied to indexing and force-merge operations.

POST my-vector-index/_bulk
{"index": {"_id": "1"}}
{"vector_field": [0.1, 0.2, 0.3, ...], "text": "Sample document 1"}
{"index": {"_id": "2"}}
{"vector_field": [0.4, 0.5, 0.6, ...], "text": "Sample document 2"}

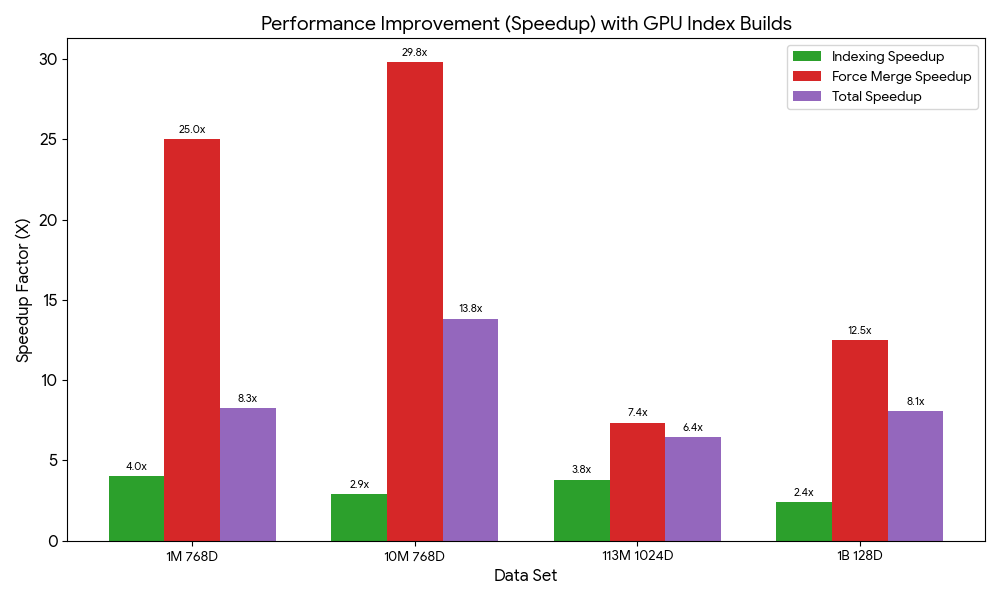
We ran index build benchmarks and observed speed gains from GPU acceleration ranging between 6.4 to 13.8 times. Stay tuned for more benchmarks and further details in upcoming posts.

To learn more, visit GPU acceleration for vector indexing in the Amazon OpenSearch Service Developer Guide.

Auto-optimizing vector databases
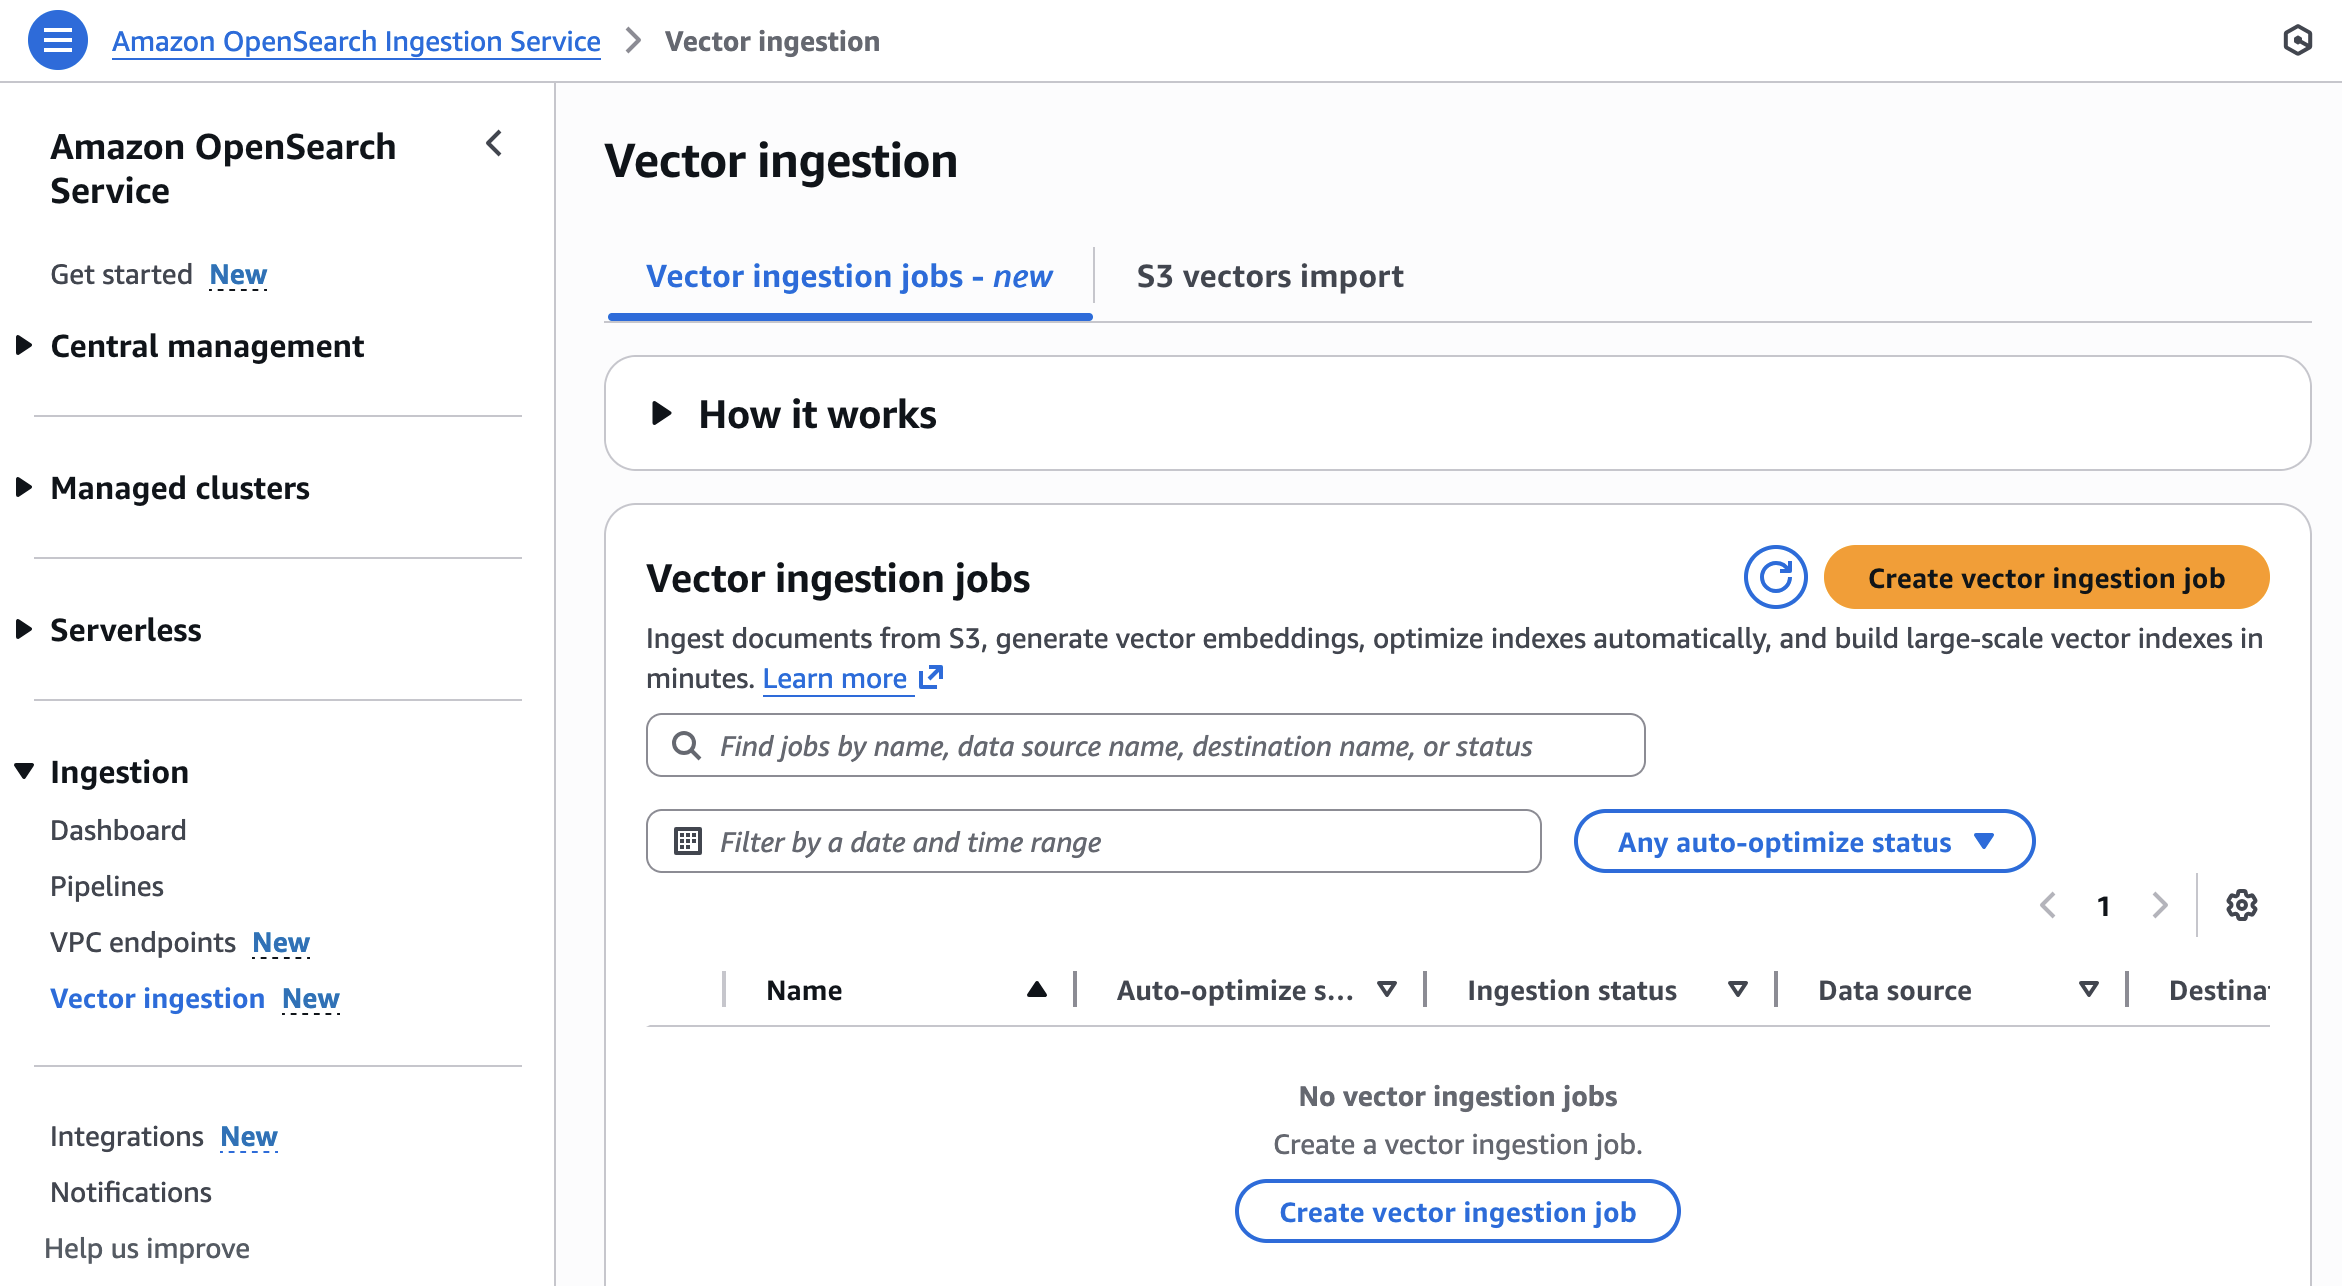
You can use the new vector ingestion feature to ingest documents from Amazon Simple Storage Service (Amazon S3), generate vector embeddings, optimize indexes automatically, and build large-scale vector indexes in minutes. During the ingestion, auto-optimization generates recommendations based on your vector fields and indexes of your OpenSearch Service domain or Serverless collection. You can choose one of these recommendations to quickly ingest and index your vector dataset instead of manually configuring these mappings.

To get started, choose Vector ingestion under the Ingestion menu in the left navigation pane of OpenSearch Service console.

You can create a new vector ingestion job with the following steps:

  • Prepare dataset – Prepare OpenSearch Service parquet documents in an S3 bucket and choose a domain or collection for your destination.
  • Configure index and automate optimizations – Auto-optimize your vector fields or manually configure them.
  • Ingest and accelerate indexing – Use OpenSearch ingestion pipelines to load data from Amazon S3 into OpenSearch Service. Build large vector indexes up to 10 times faster at a quarter of the cost.

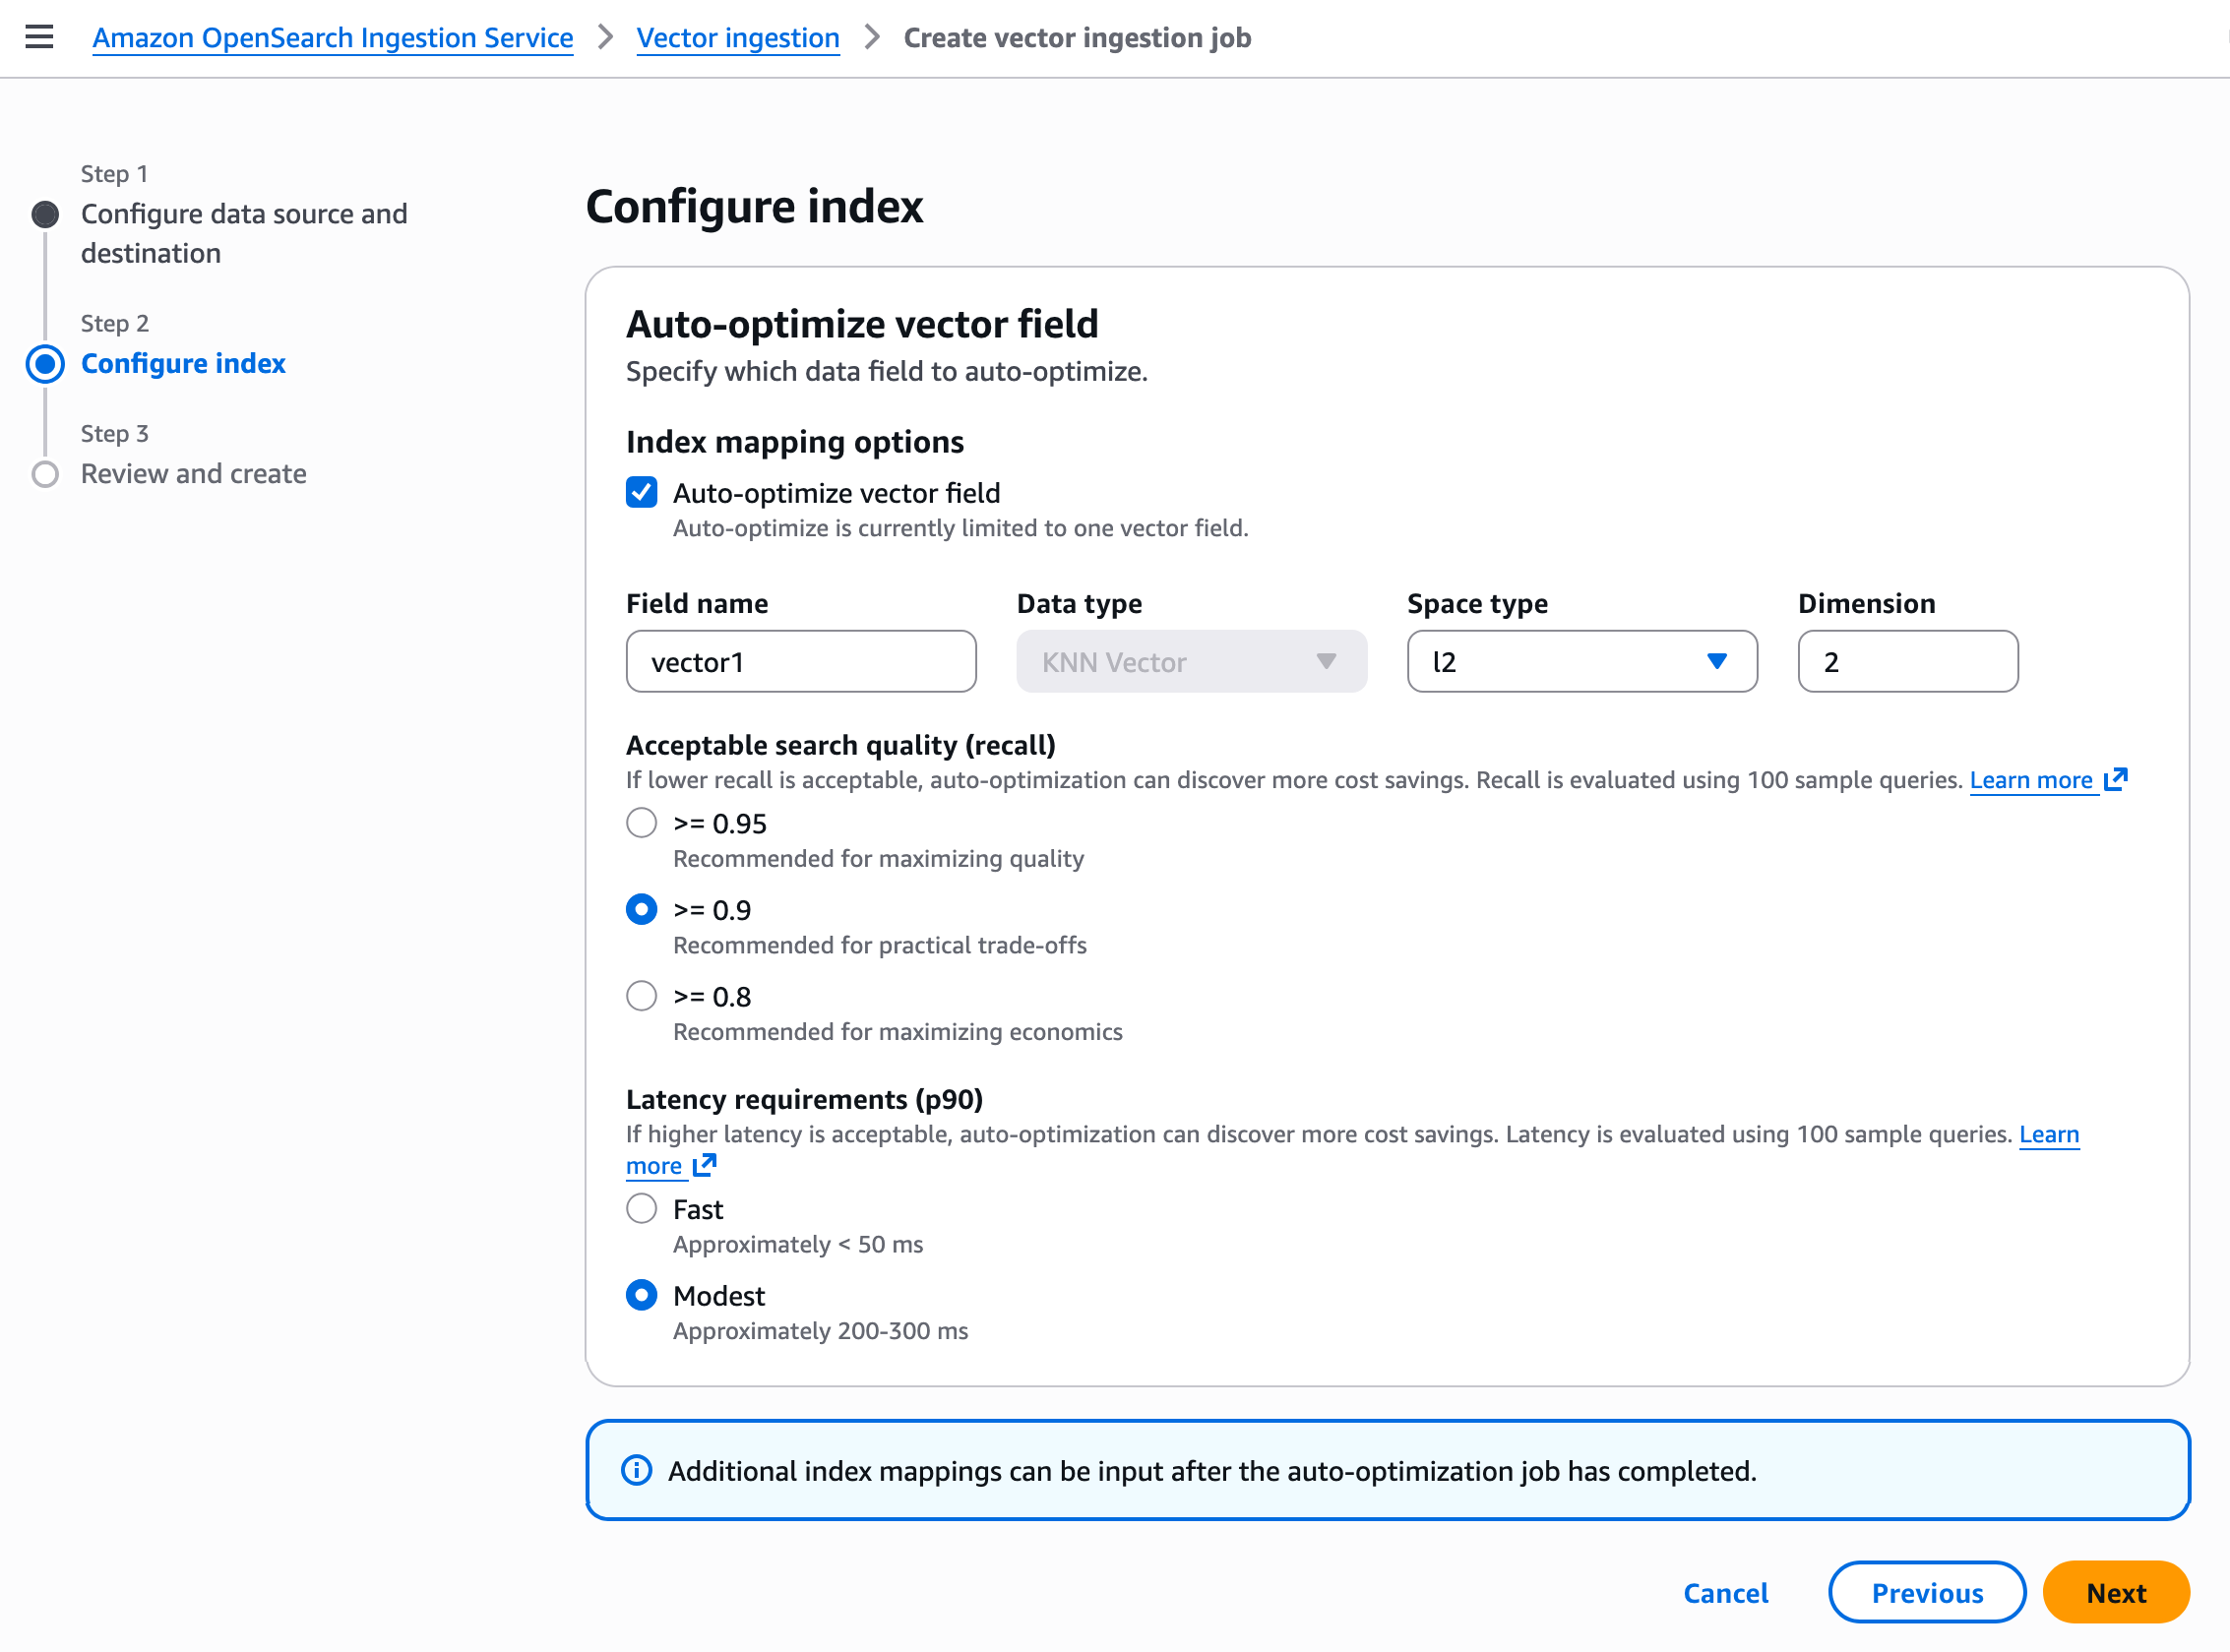
In Step 2, configure your vector index with auto-optimize vector field. Auto-optimize is currently limited to one vector field. Further index mappings can be input after the auto-optimization job has completed.

Your vector field optimization settings depend on your use case. For example, if you need high search quality (recall rate) and don’t need faster responses, then choose Modest for the Latency requirements (p90) and more than or equal to 0.9 for the Acceptable search quality (recall). When you create a job, it starts to ingest vector data and auto-optimize vector index. The processing time depends on the vector dimensionality.

To learn more, visit Auto-optimize vector index in the OpenSearch Service Developer Guide.

Now available
GPU acceleration in Amazon OpenSearch Service is now available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Sydney), Asia Pacific (Tokyo), and Europe (Ireland) Regions. Auto-optimization in OpenSearch Service is now available in the US East (Ohio), US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Europe (Frankfurt), and Europe (Ireland) Regions.

OpenSearch Service separately charges for used OCU – Vector Acceleration only to index your vector databases. For more information, visitOpenSearch Service pricing page.

Give it a try and send feedback to the AWS re:Post for Amazon OpenSearch Service or through your usual AWS Support contacts.

— Channy

Amazon S3 Vectors now generally available with increased scale and performance

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-s3-vectors-now-generally-available-with-increased-scale-and-performance/

Today, I’m excited to announce that Amazon S3 Vectors is now generally available with significantly increased scale and production-grade performance capabilities. S3 Vectors is the first cloud object storage with native support to store and query vector data. You can use it to help you reduce the total cost of storing and querying vectors by up to 90% when compared to specialized vector database solutions.

Since we announced the preview of S3 Vectors in July, I’ve been impressed by how quickly you adopted this new capability to store and query vector data. In just over four months, you created over 250,000 vector indexes and ingested more than 40 billion vectors, performing over 1 billion queries (as of November 28th).

You can now store and search across up to 2 billion vectors in a single index, that’s up to 20 trillion vectors in a vector bucket and a 40x increase from 50 million per index during preview. This means that you can consolidate your entire vector dataset into one index, removing the need to shard across multiple smaller indexes or implement complex query federation logic.

Query performance has been optimized. Infrequent queries continue to return results in under one second, with more frequent queries now resulting in latencies around 100ms or less, making it well-suited for interactive applications such as conversational AI and multi-agent workflows. You can also retrieve up to 100 search results per query, up from 30 previously, providing more comprehensive context for retrieval augmented generation (RAG) applications.

The write performance has also improved substantially, with support for up to 1,000 PUT transactions per second when streaming single-vector updates into your indexes, delivering significantly higher write throughput for small batch sizes. This higher throughput supports workloads where new data must be immediately searchable, helping you ingest small data corpora quickly or handle many concurrent sources writing simultaneously to the same index.

The fully serverless architecture removes infrastructure overhead—there’s no infrastructure to set up or resources to provision. You pay for what you use as you store and query vectors. This AI-ready storage provides you with quick access to any amount of vector data to support your complete AI development lifecycle, from initial experimentation and prototyping through to large-scale production deployments. S3 Vectors now provides the scale and performance needed for production workloads across AI agents, inference, semantic search, and RAG applications.

Two key integrations that were launched in preview are now generally available. You can use S3 Vectors as a vector storage engine for Amazon Bedrock Knowledge Base. In particular, you can use it to build RAG applications with production-grade scale and performance. Moreover, S3 Vectors integration with Amazon OpenSearch is now generally available, so that you can use S3 Vectors as your vector storage layer while using OpenSearch for search and analytics capabilities.

You can now use S3 Vectors in 14 AWS Regions, expanding from five AWS Regions during the preview.

Let’s see how it works
In this post, I demonstrate how to use S3 Vectors through the AWS Console and CLI.

First, I create an S3 Vector bucket and an index.

echo "Creating S3 Vector bucket..."
aws s3vectors create-vector-bucket \
    --vector-bucket-name "$BUCKET_NAME"

echo "Creating vector index..."
aws s3vectors create-index \
    --vector-bucket-name "$BUCKET_NAME" \
    --index-name "$INDEX_NAME" \
    --data-type "float32" \
    --dimension "$DIMENSIONS" \
    --distance-metric "$DISTANCE_METRIC" \
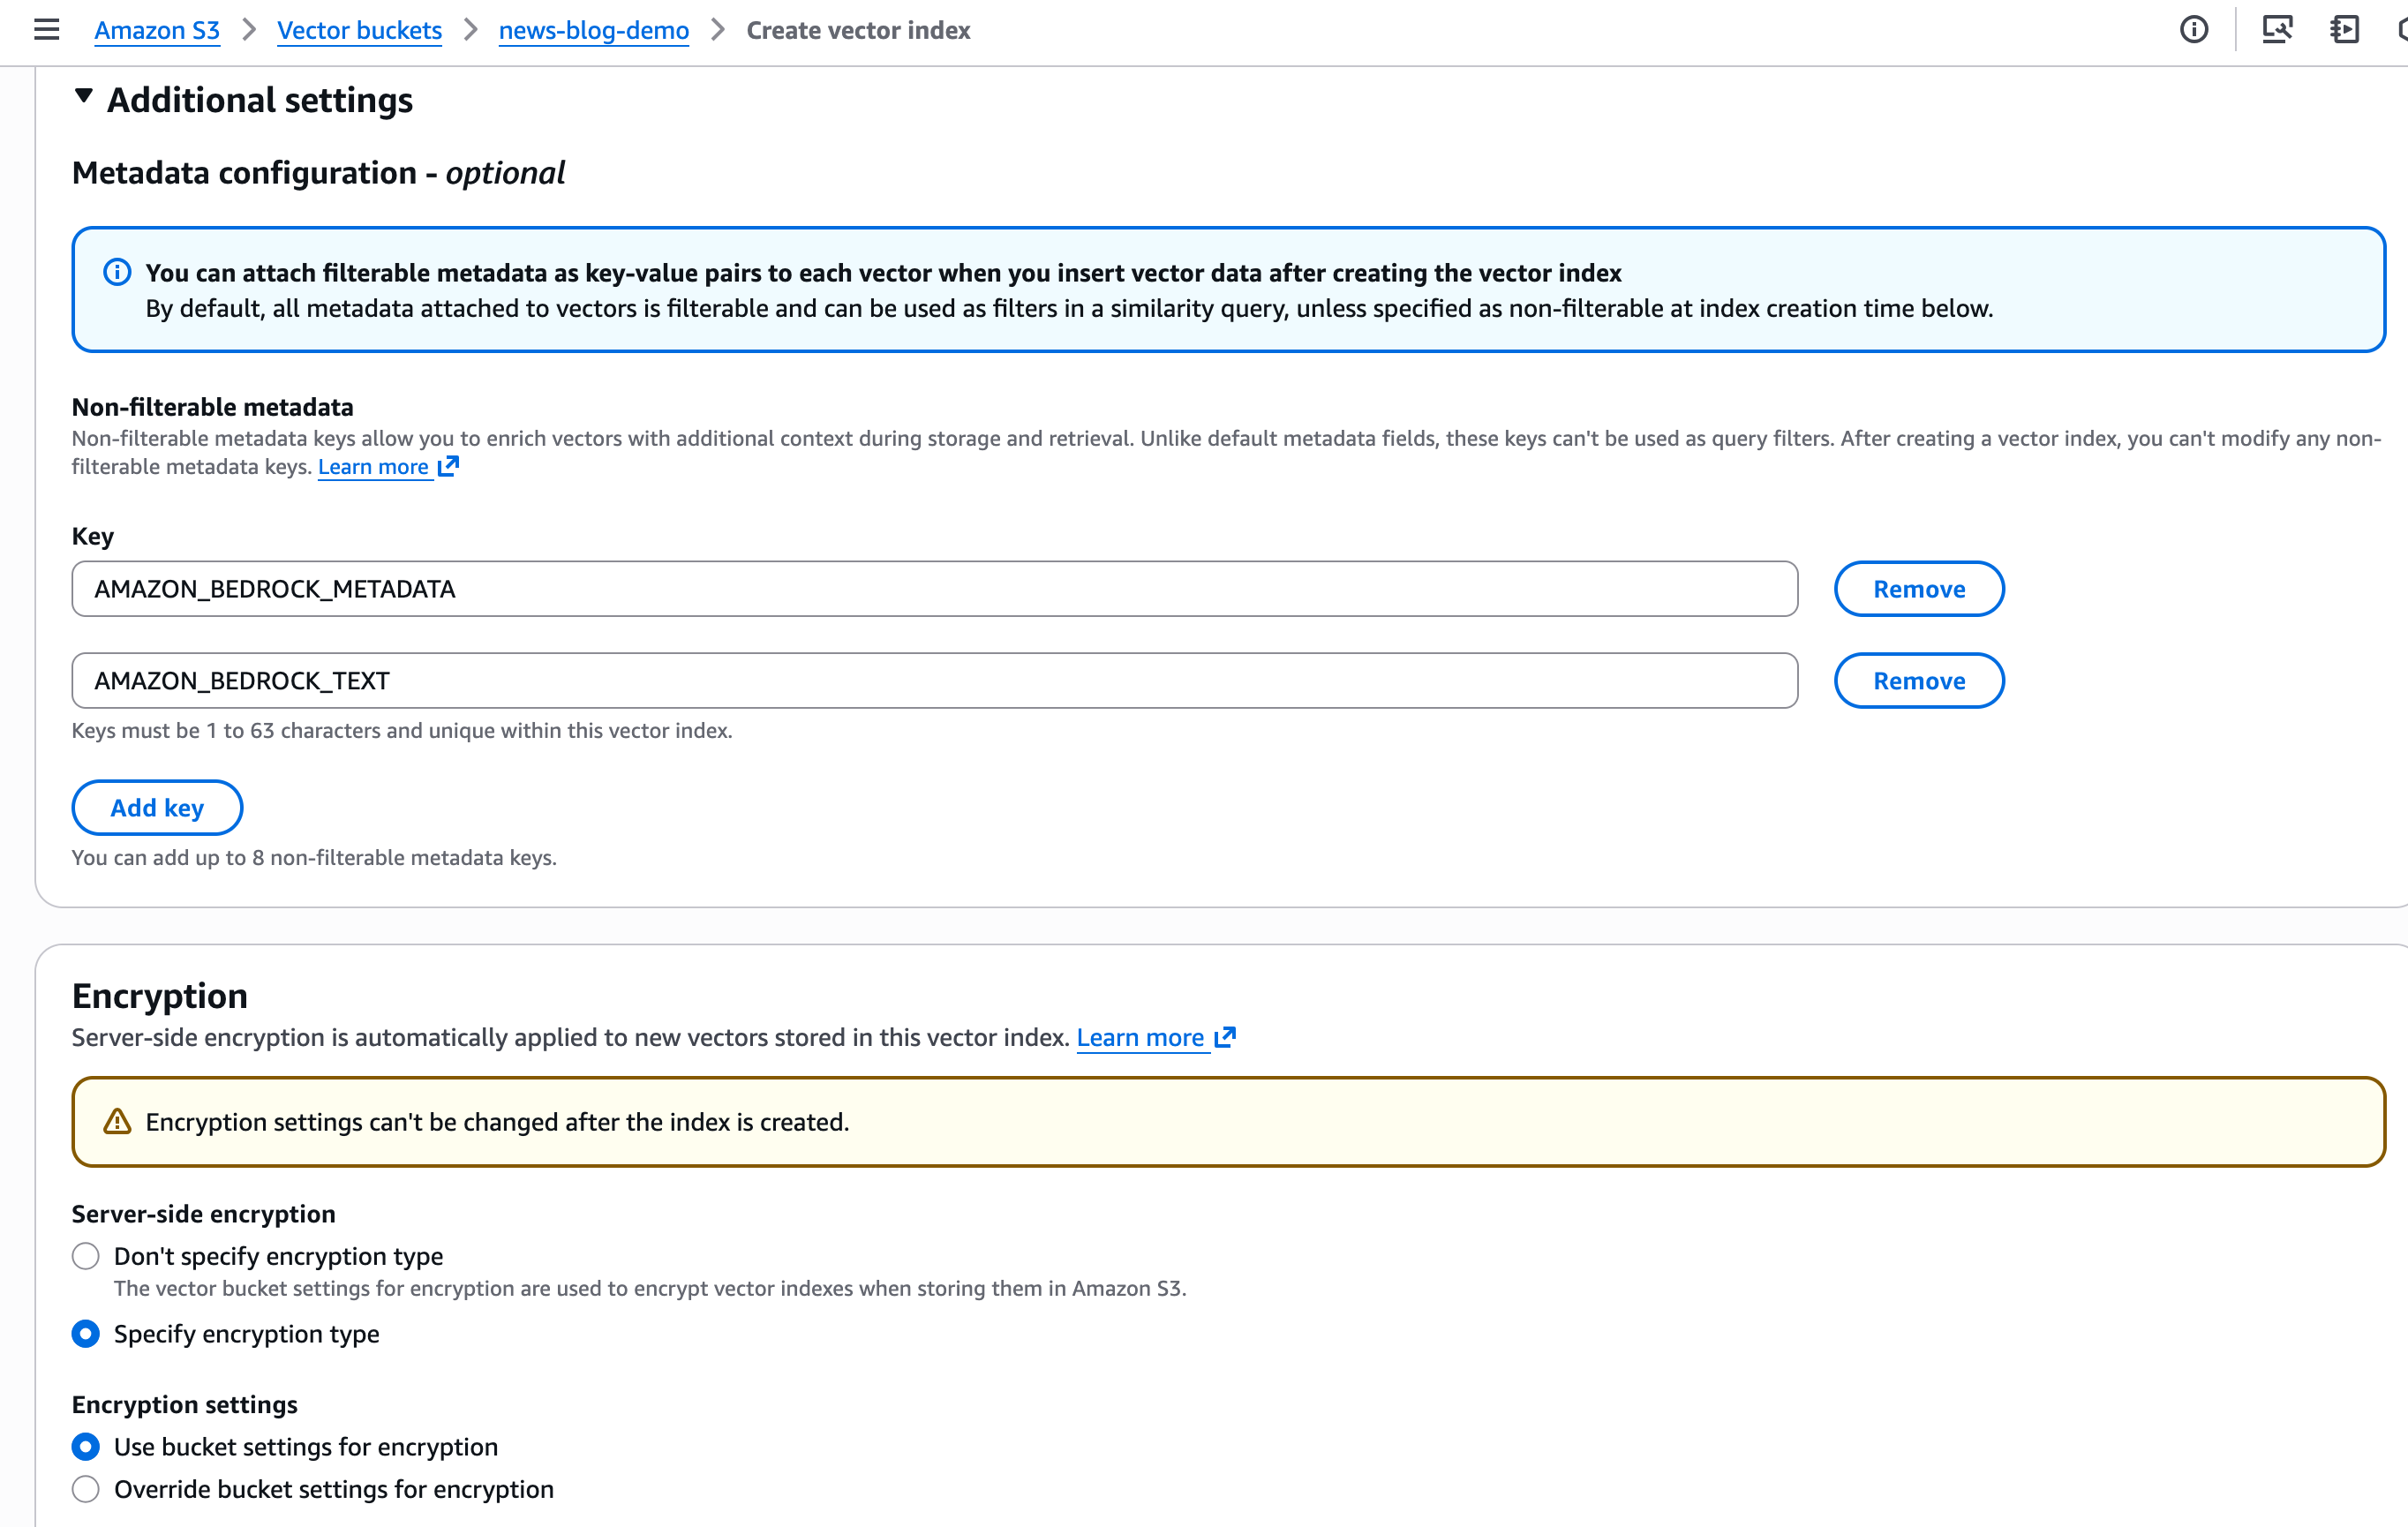
    --metadata-configuration "nonFilterableMetadataKeys=AMAZON_BEDROCK_TEXT,AMAZON_BEDROCK_METADATA"

The dimension metric must match the dimension of the model used to compute the vectors. The distance metric indicates to the algorithm to compute the distance between vectors. S3 Vectors supports cosine and euclidian distances.

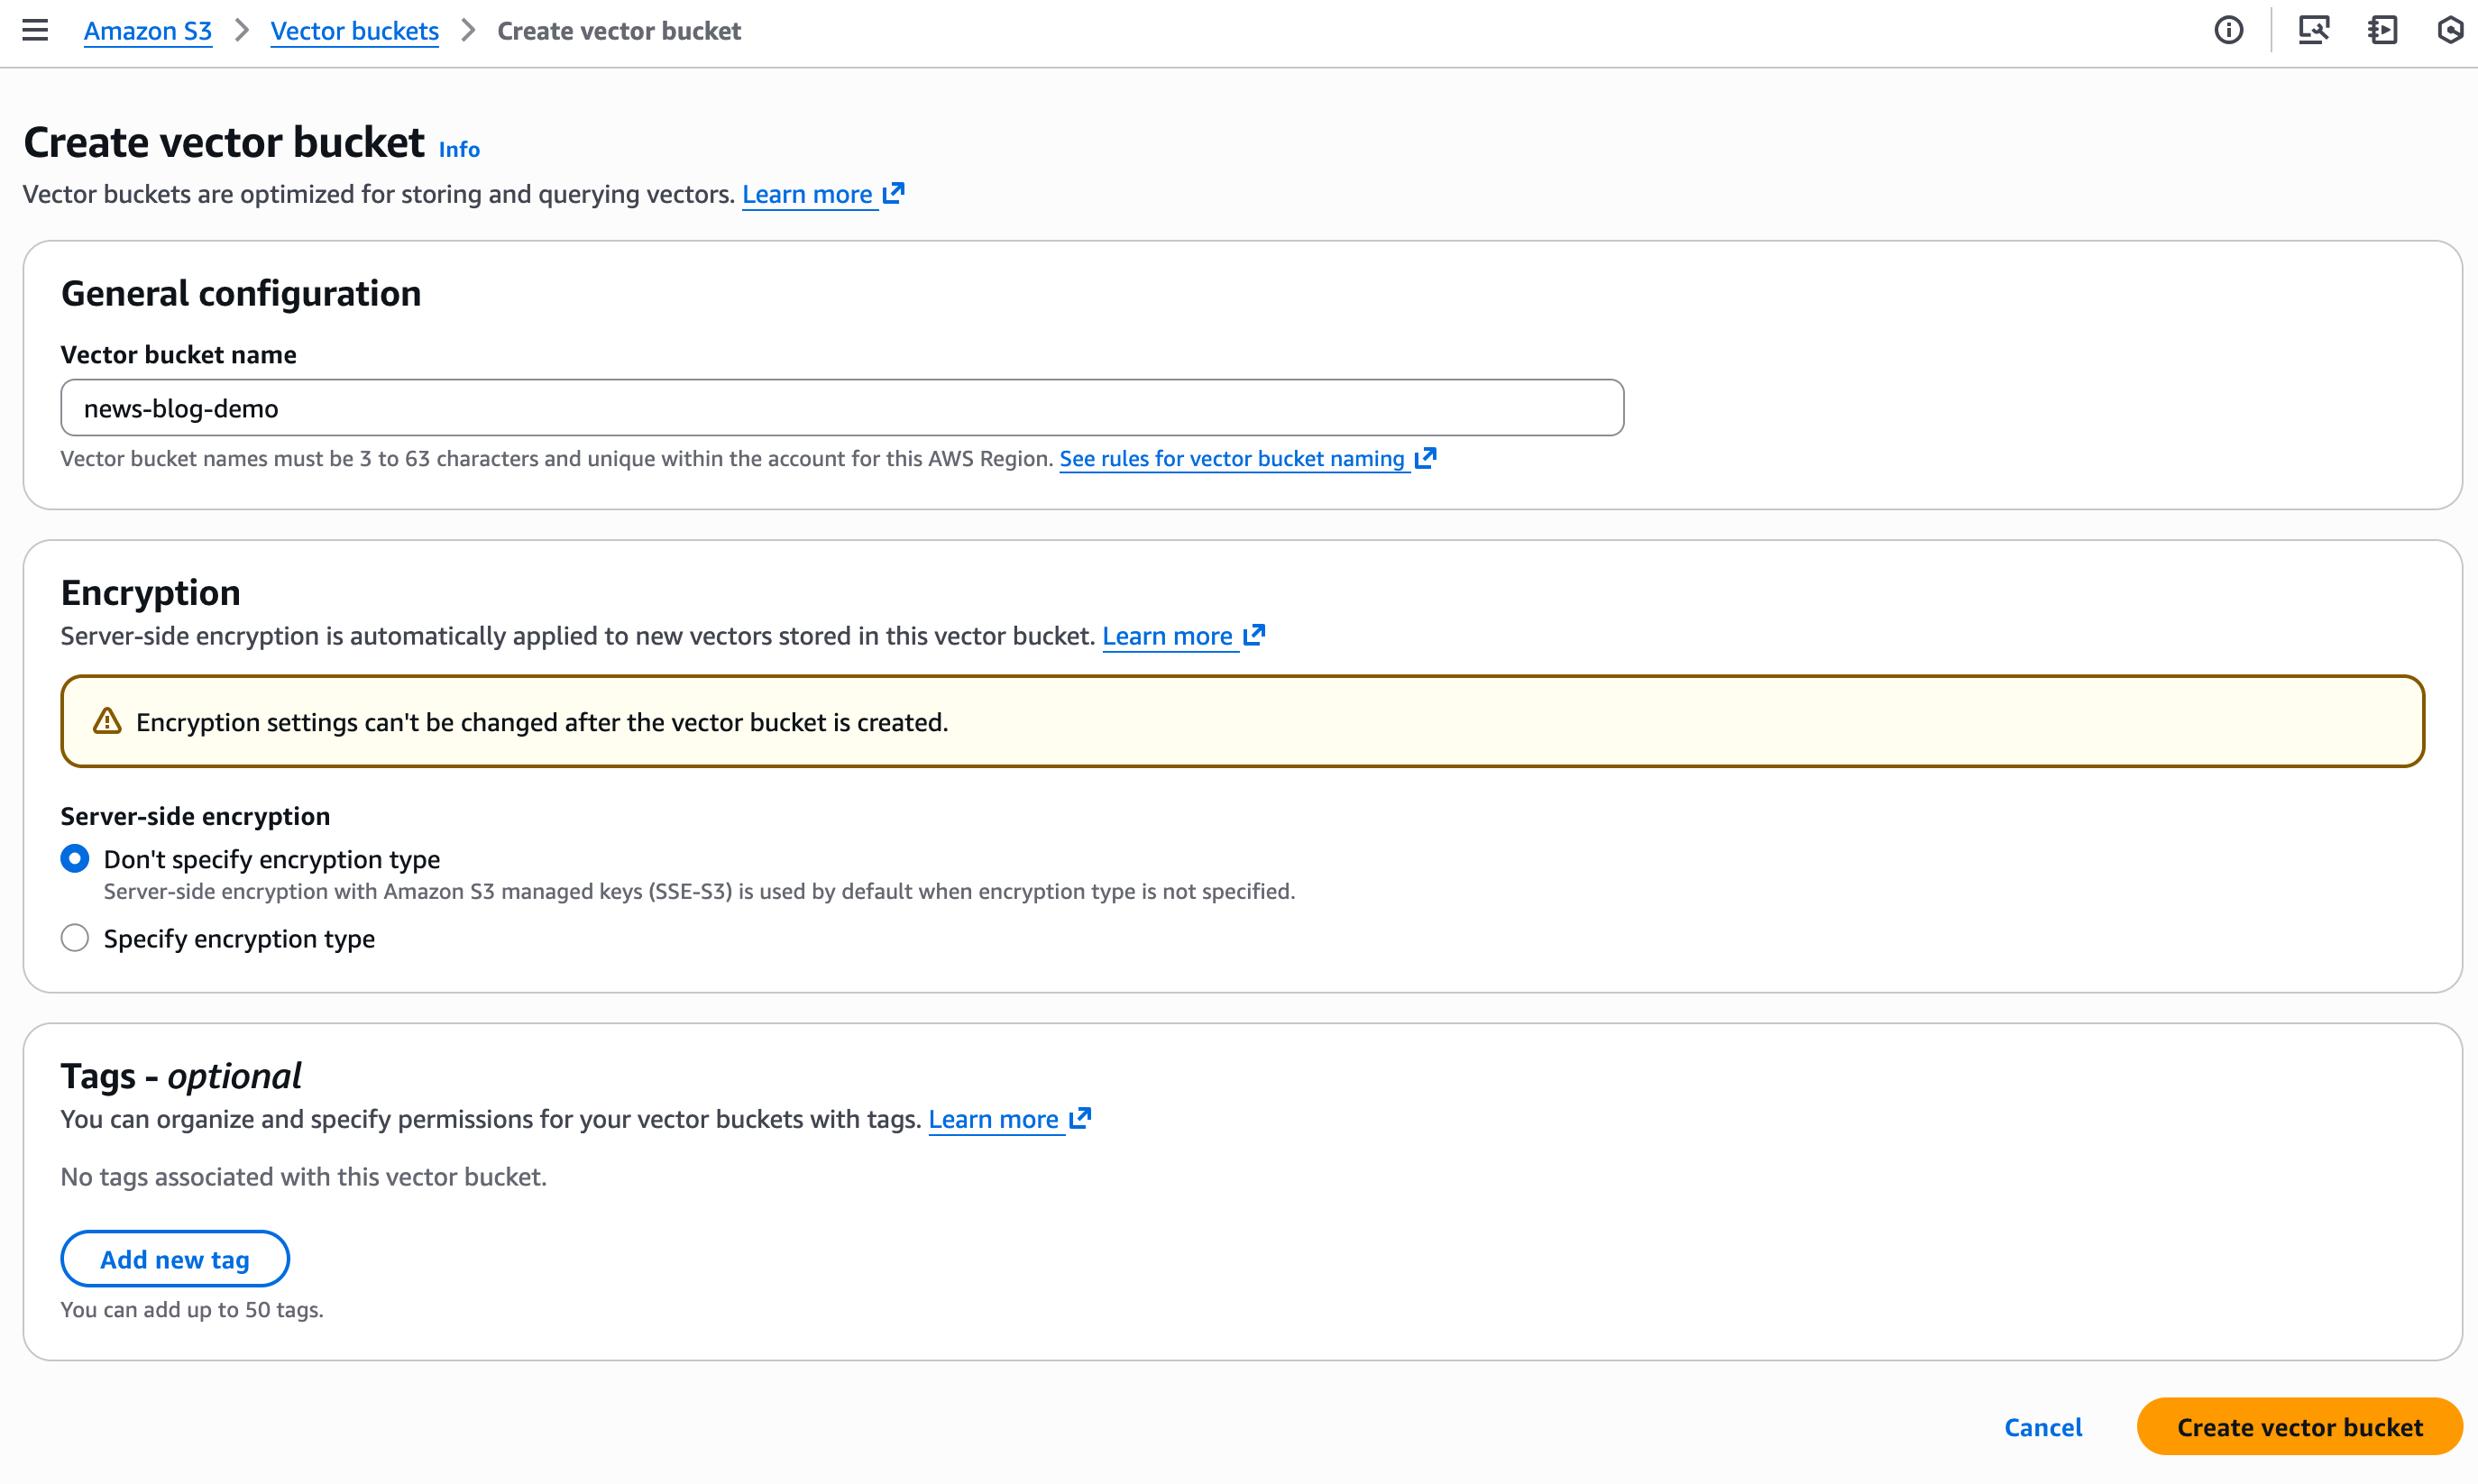
I can also use the console to create the bucket. We’ve added the capability to configure encryption parameters at creation time. By default, indexes use the bucket-level encryption, but I can override bucket-level encryption at the index level with a custom AWS Key Management Service (AWS KMS) key.

I also can add tags for the vector bucket and vector index. Tags at the vector index help with access control and cost allocation.

S3 Vector console - create

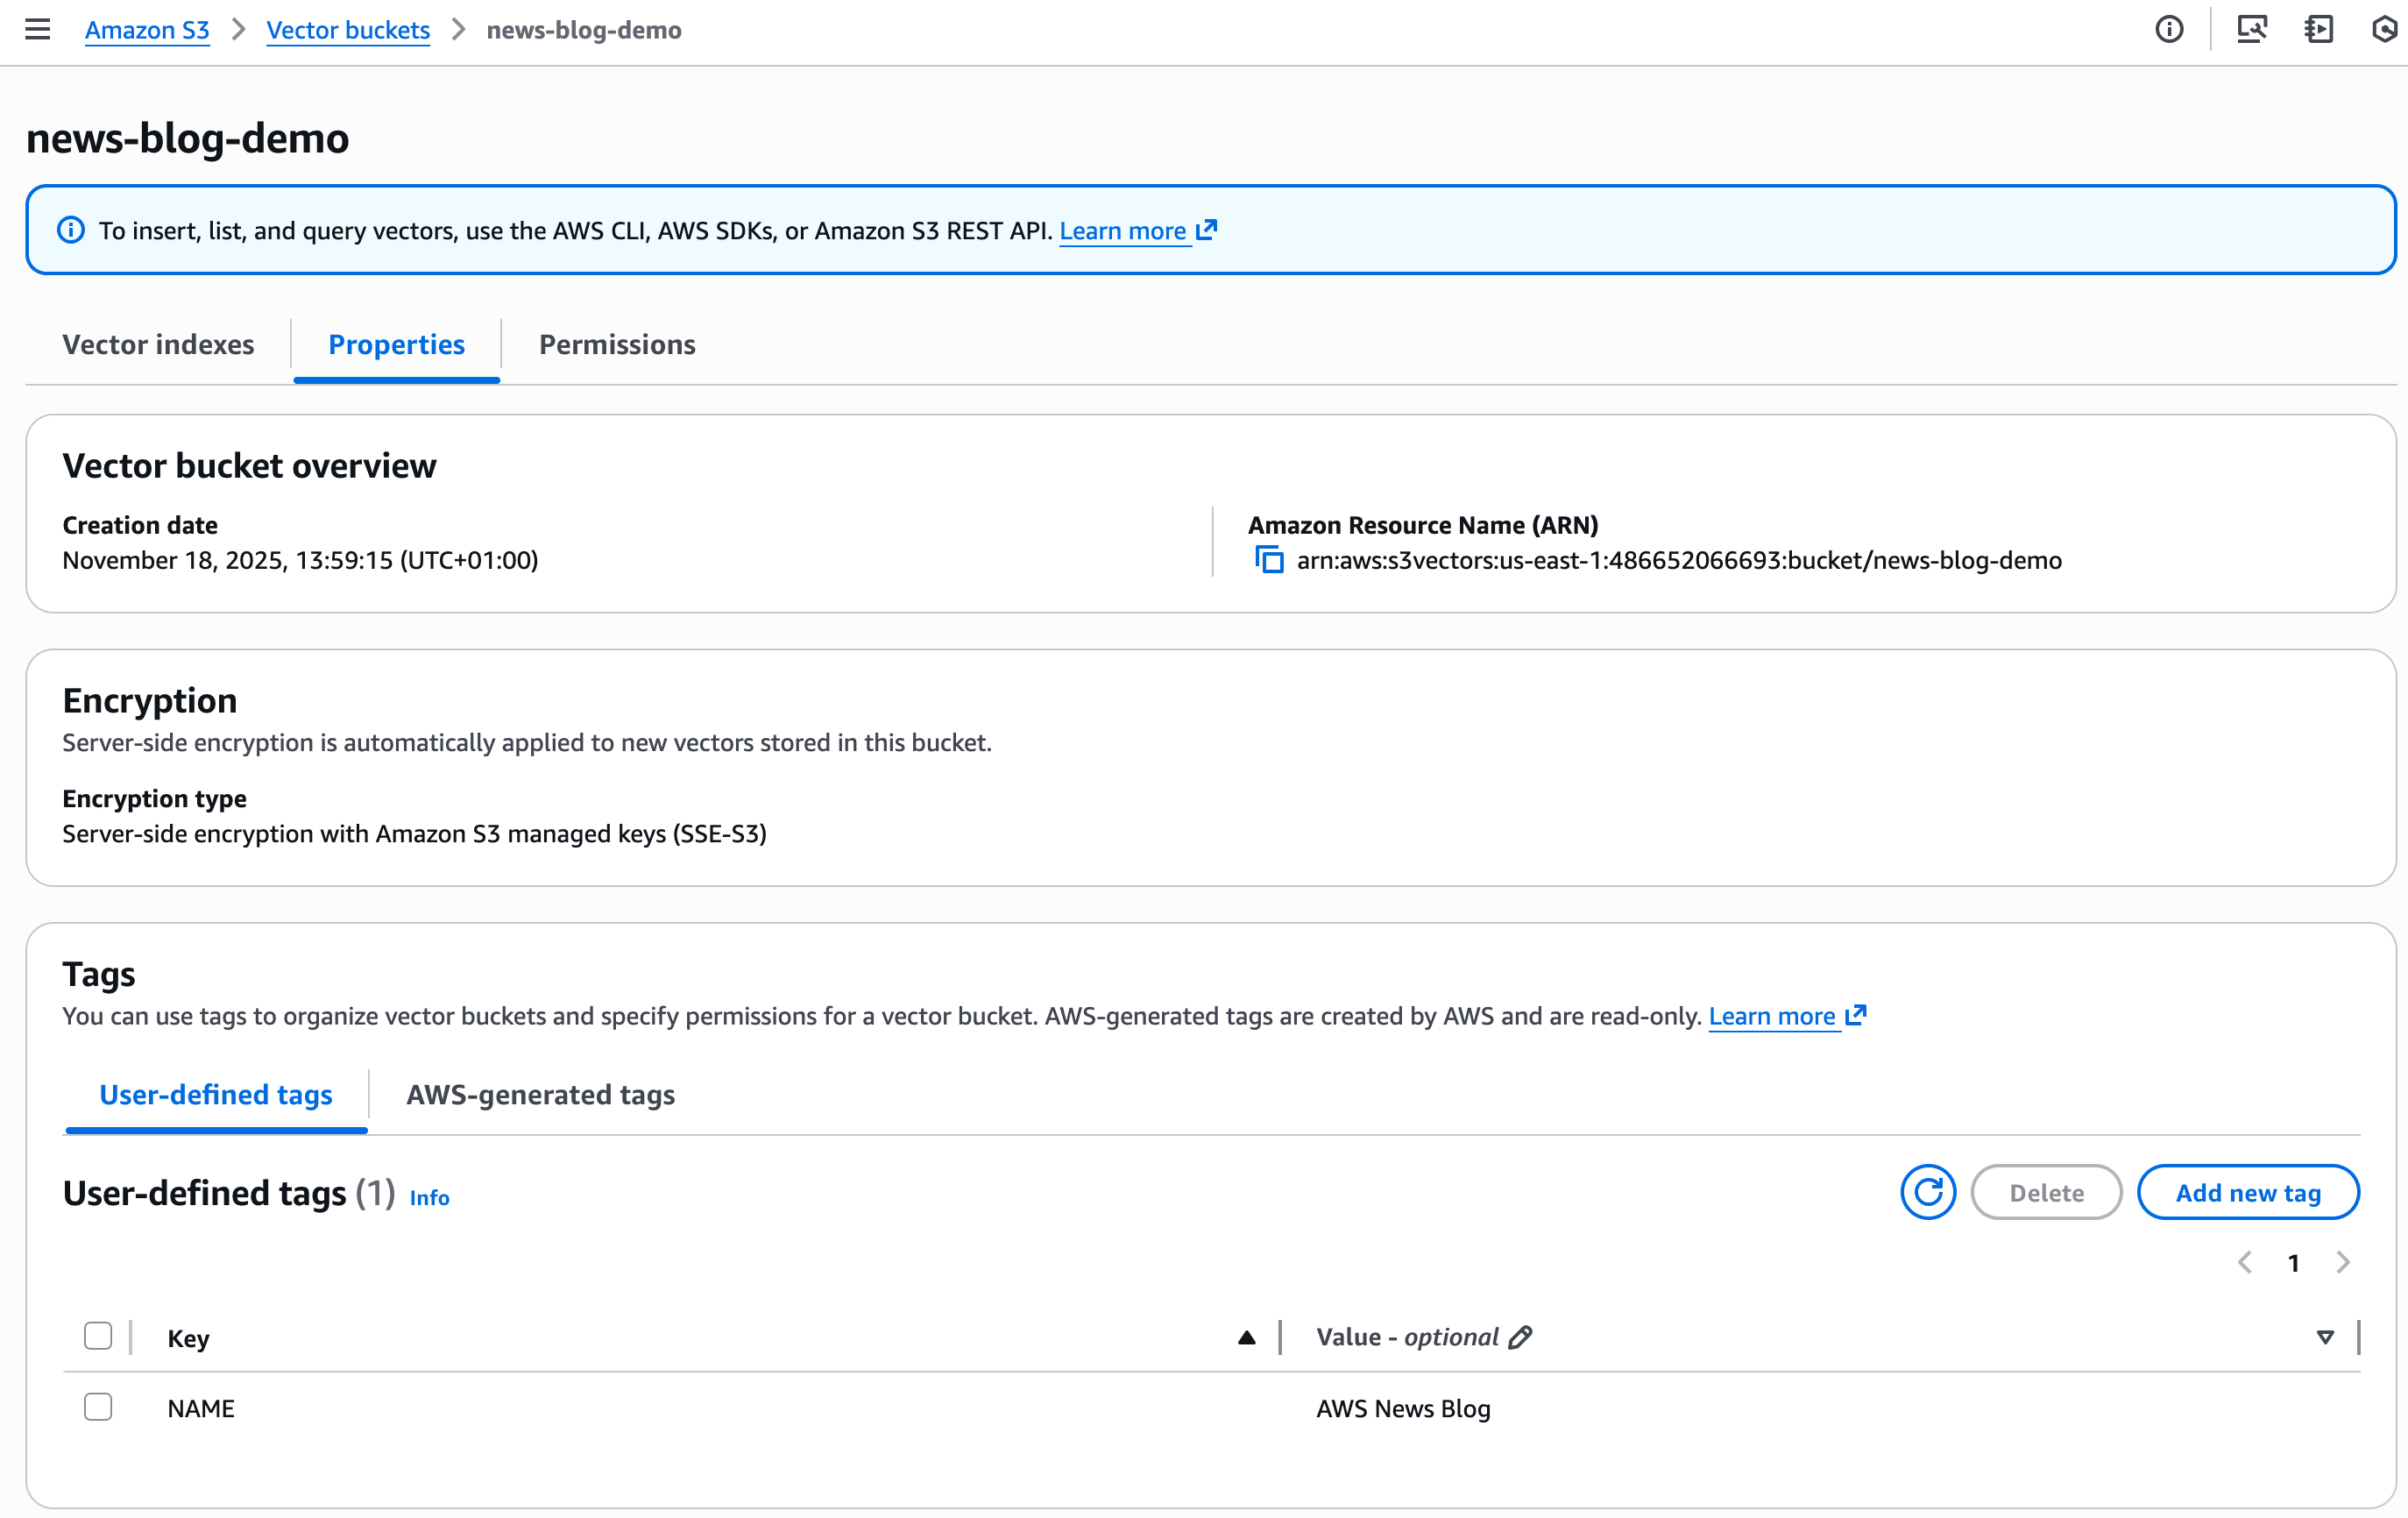
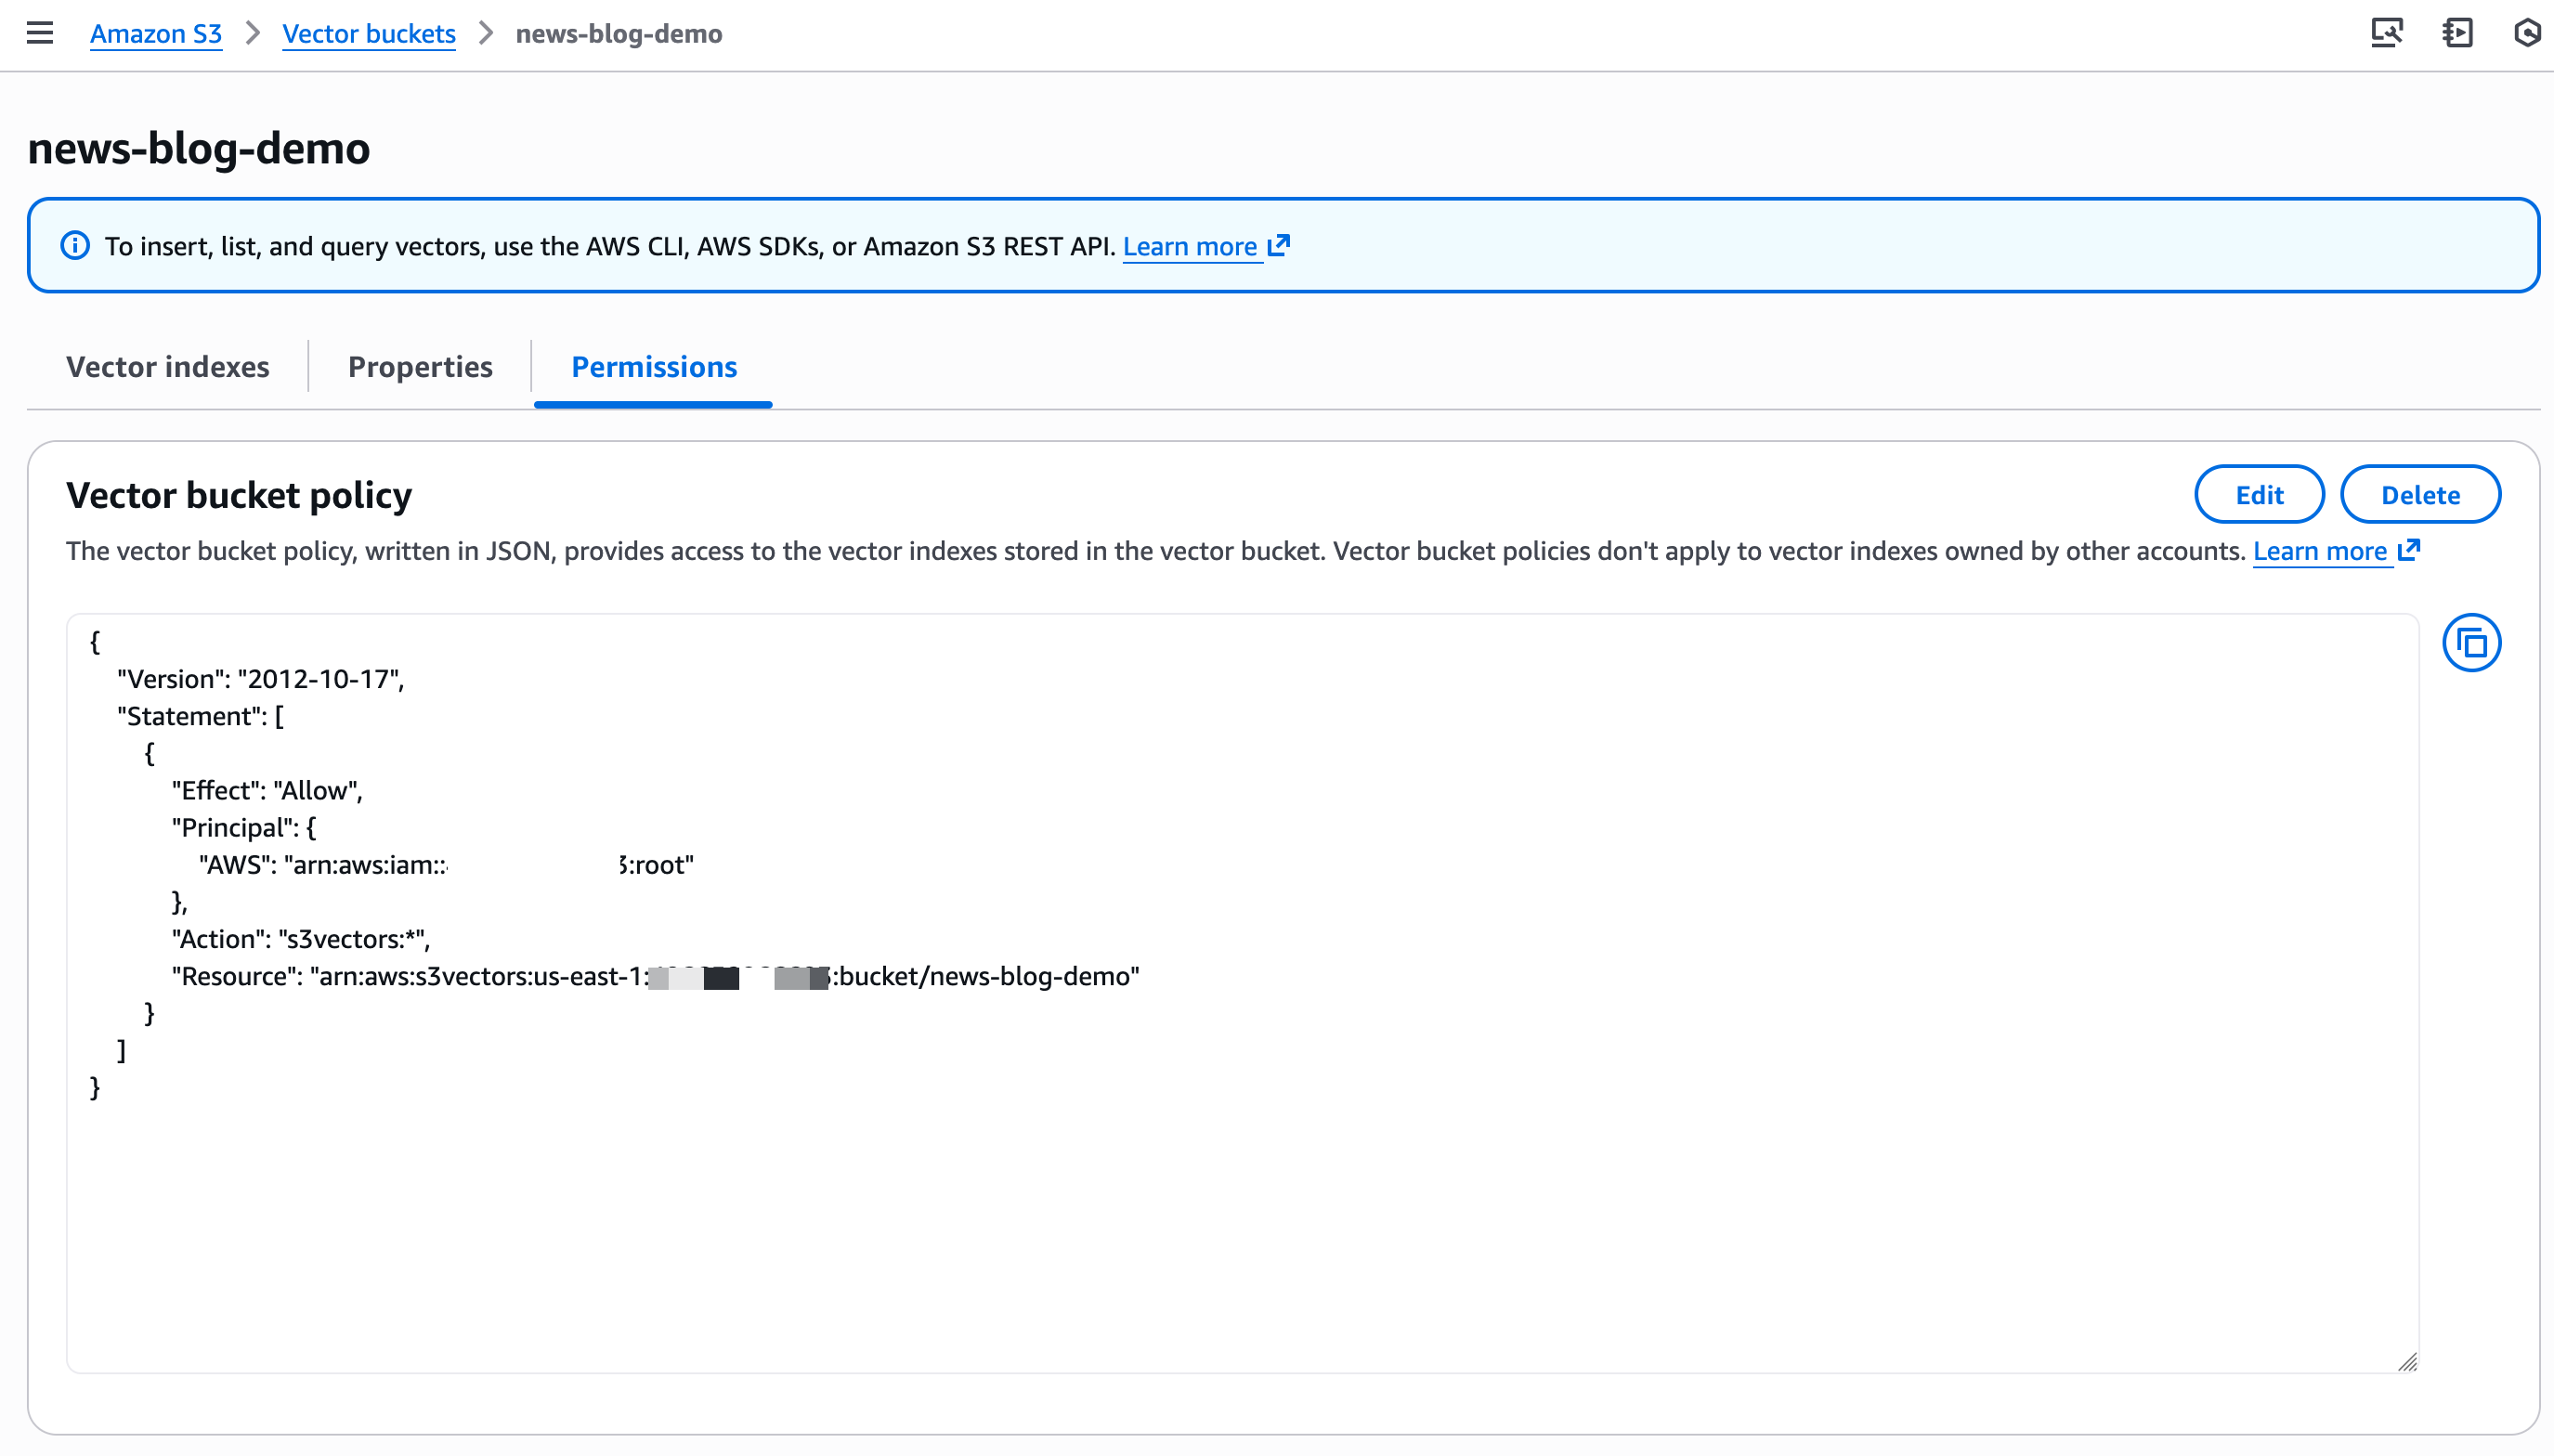
And I can now manage Properties and Permissions directly in the console.

S3 Vector console - properties

S3 Vector console - create

Similarly, I define Non-filterable metadata and I configure Encryption parameters for the vector index.

S3 Vector console - create index

Next, I create and store the embeddings (vectors). For this demo, I ingest my constant companion: the AWS Style Guide. This is an 800-page document that describes how to write posts, technical documentation, and articles at AWS.

I use Amazon Bedrock Knowledge Bases to ingest the PDF document stored on a general purpose S3 bucket. Amazon Bedrock Knowledge Bases reads the document and splits it in pieces called chunks. Then, it computes the embeddings for each chunk with the Amazon Titan Text Embeddings model and it stores the vectors and their metadata on my newly created vector bucket. The detailed steps for that process are out of the scope of this post, but you can read the instructions in the documentation.

When querying vectors, you can store up to 50 metadata keys per vector, with up to 10 marked as non-filterable. You can use the filterable metadata keys to filter query results based on specific attributes. Therefore, you can combine vector similarity search with metadata conditions to narrow down results. You can also store more non-filterable metadata for larger contextual information. Amazon Bedrock Knowledge Bases computes and stores the vectors. It also adds large metadata (the chunk of the original text). I exclude this metadata from the searchable index.

There are other methods to ingest your vectors. You can try the S3 Vectors Embed CLI, a command line tool that helps you generate embeddings using Amazon Bedrock and store them in S3 Vectors through direct commands. You can also use S3 Vectors as a vector storage engine for OpenSearch.

Now I’m ready to query my vector index. Let’s imagine I wonder how to write “open source”. Is it “open-source”, with a hyphen, or “open source” without a hyphen? Should I use uppercase or not? I want to search the relevant sections of the AWS Style Guide relative to “open source.”

# 1. Create embedding request
echo '{"inputText":"Should I write open source or open-source"}' | base64 | tr -d '\n' > body_encoded.txt

# 2. Compute the embeddings with Amazon Titan Embed model
aws bedrock-runtime invoke-model \
  --model-id amazon.titan-embed-text-v2:0 \
  --body "$(cat body_encoded.txt)" \
  embedding.json

# Search the S3 Vectors index for similar chunks
vector_array=$(cat embedding.json | jq '.embedding') && \
aws s3vectors query-vectors \
  --index-arn "$S3_VECTOR_INDEX_ARN" \
  --query-vector "{\"float32\": $vector_array}" \
  --top-k 3 \
  --return-metadata \
  --return-distance | jq -r '.vectors[] | "Distance: \(.distance) | Source: \(.metadata."x-amz-bedrock-kb-source-uri" | split("/")[-1]) | Text: \(.metadata.AMAZON_BEDROCK_TEXT[0:100])..."'

The first result shows this JSON:

        {
            "key": "348e0113-4521-4982-aecd-0ee786fa4d1d",
            "metadata": {
                "x-amz-bedrock-kb-data-source-id": "0SZY6GYPVS",
                "x-amz-bedrock-kb-source-uri": "s3://sst-aws-docs/awsstyleguide.pdf",
                "AMAZON_BEDROCK_METADATA": "{\"createDate\":\"2025-10-21T07:49:38Z\",\"modifiedDate\":\"2025-10-23T17:41:58Z\",\"source\":{\"sourceLocation\":\"s3://sst-aws-docs/awsstyleguide.pdf\"",
                "AMAZON_BEDROCK_TEXT": "[redacted] open source (adj., n.) Two words. Use open source as an adjective (for example, open source software), or as a noun (for example, the code throughout this tutorial is open source). Don't use open-source, opensource, or OpenSource. [redacted]",
                "x-amz-bedrock-kb-document-page-number": 98.0
            },
            "distance": 0.63120436668396
        }

It finds the relevant section in the AWS Style Guide. I must write “open source” without a hyphen. It even retrieved the page number in the original document to help me cross-check the suggestion with the relevant paragraph in the source document.

One more thing
S3 Vectors has also expanded its integration capabilities. You can now use AWS CloudFormation to deploy and manage your vector resources, AWS PrivateLink for private network connectivity, and resource tagging for cost allocation and access control.

Pricing and availability
S3 Vectors is now available in 14 AWS Regions, adding Asia Pacific (Mumbai, Seoul, Singapore, Tokyo), Canada (Central), and Europe (Ireland, London, Paris, Stockholm) to the existing five Regions from preview (US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Sydney), and Europe (Frankfurt))

Amazon S3 Vectors pricing is based on three dimensions. PUT pricing is calculated based on the logical GB of vectors you upload, where each vector includes its logical vector data, metadata, and key. Storage costs are determined by the total logical storage across your indexes. Query charges include a per-API charge plus a $/TB charge based on your index size (excluding non-filterable metadata). As your index scales beyond 100,000 vectors, you benefit from lower $/TB pricing. As usual, the Amazon S3 pricing page has the details.

To get started with S3 Vectors, visit the Amazon S3 console. You can create vector indexes, start storing your embeddings, and begin building scalable AI applications. For more information, check out the Amazon S3 User Guide or the AWS CLI Command Reference.

I look forward to seeing what you build with these new capabilities. Please share your feedback through AWS re:Post or your usual AWS Support contacts.

— seb

Amazon Bedrock adds 18 fully managed open weight models, including the new Mistral Large 3 and Ministral 3 models

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-bedrock-adds-fully-managed-open-weight-models/

Today, we’re announcing the general availability of an additional 18 fully managed open weight models in Amazon Bedrock from Google, Moonshot AI, MiniMax AI, Mistral AI, NVIDIA, OpenAI, and Qwen, including the new Mistral Large 3 and Ministral 3 3B, 8B, and 14B models.

With this launch, Amazon Bedrock now provides nearly 100 serverless models, offering a broad and deep range of models from leading AI companies, so customers can choose the precise capabilities that best serve their unique needs. By closely monitoring both customer needs and technological advancements, we regularly expand our curated selection of models based on customer needs and technological advancements to include promising new models alongside established industry favorites.

This ongoing expansion of high-performing and differentiated model offerings helps customers stay at the forefront of AI innovation. You can access these models on Amazon Bedrock through the unified API, evaluate, switch, and adopt new models without rewriting applications or changing infrastructure.

New Mistral AI models
These four Mistral AI models are now available first on Amazon Bedrock, each optimized for different performance and cost requirements:

  • Mistral Large 3 – This open weight model is optimized for long-context, multimodal, and instruction reliability. It excels in long document understanding, agentic and tool use workflows, enterprise knowledge work, coding assistance, advanced workloads such as math and coding tasks, multilingual analysis and processing, and multimodal reasoning with vision.
  • Ministral 3 3B – The smallest in the Ministral 3 family is edge-optimized for single GPU deployment with strong language and vision capabilities. It shows robust performance in image captioning, text classification, real-time translation, data extraction, short content generation, and lightweight real-time applications on edge or low-resource devices.
  • Ministral 3 8B – The best-in-class Ministral 3 model for text and vision is edge-optimized for single GPU deployment with high performance and minimal footprint. This model is ideal for chat interfaces in constrained environments, image and document description and understanding, specialized agentic use cases, and balanced performance for local or embedded systems.
  • Ministral 3 14B – The most capable Ministral 3 model delivers state-of the-art text and vision performance optimized for single GPU deployment. You can use advanced local agentic use cases and private AI deployments where advanced capabilities meet practical hardware constraints.

More open weight model options
You can use these open weight models for a wide range of use cases across industries:

Model provider Model name Description Use cases
Google Gemma 3 4B Efficient text and image model that runs locally on laptops. Multilingual support for on-device AI applications. On-device AI for mobile and edge applications, privacy-sensitive local inference, multilingual chat assistants, image captioning and description, and lightweight content generation.
Gemma 3 12B Balanced text and image model for workstations. Multi-language understanding with local deployment for privacy-sensitive applications. Workstation-based AI applications; local deployment for enterprises; multilingual document processing, image analysis and Q&A; and privacy-compliant AI assistants.
Gemma 3 27B Powerful text and image model for enterprise applications. Multi-language support with local deployment for privacy and control. Enterprise local deployment, high-performance multimodal applications, advanced image understanding, multilingual customer service, and data-sensitive AI workflows.
Moonshot AI Kimi K2 Thinking Deep reasoning model that thinks while using tools. Handles research, coding and complex workflows requiring hundreds of sequential actions. Complex coding projects requiring planning, multistep workflows, data analysis and computation, and long-form content creation with research.
MiniMax AI MiniMax M2 Built for coding agents and automation. Excels at multi-file edits, terminal operations and executing long tool-calling chains efficiently. Coding agents and integrated development environment (IDE) integration, multi-file code editing, terminal automation and DevOps, long-chain tool orchestration, and agentic software development.
Mistral AI Magistral Small 1.2 Excels at math, coding, multilingual tasks, and multimodal reasoning with vision capabilities for efficient local deployment. Math and coding tasks, multilingual analysis and processing, and multimodal reasoning with vision.
Voxtral Mini 1.0 Advanced audio understanding model with transcription, multilingual support, Q&A, summarization, and function-calling. Voice-controlled applications, fast speech-to-text conversion, and offline voice assistants.
Voxtral Small 1.0 Features state-of-the-art audio input with best-in-class text performance; excels at speech transcription, translation, and understanding. Enterprise speech transcription, multilingual customer service, and audio content summarization.
NVIDIA NVIDIA Nemotron Nano 2 9B High efficiency LLM with hybrid transformer Mamba design, excelling in reasoning and agentic tasks. Reasoning, tool calling, math, coding, and instruction following.
NVIDIA Nemotron Nano 2 VL 12B Advanced multimodal reasoning model for video understanding and document intelligence, powering Retrieval-Augmented Generation (RAG) and multimodal agentic applications. Multi-image and video understanding, visual Q&A, and summarization.
OpenAI gpt-oss-safeguard-20b Content safety model that applies your custom policies. Classifies harmful content with explanations for trust and safety workflows. Content moderation and safety classification, custom policy enforcement, user-generated content filtering, trust and safety workflows, and automated content triage.
gpt-oss-safeguard-120b Larger content safety model for complex moderation. Applies custom policies with detailed reasoning for enterprise trust and safety teams. Enterprise content moderation at scale, complex policy interpretation, multilayered safety classification, regulatory compliance checking, high-stakes content review.
Qwen Qwen3-Next-80B-A3B Fast inference with hybrid attention for ultra-long documents. Optimized for RAG pipelines, tool use & agentic workflows with quick responses. RAG pipelines with long documents, agentic workflows with tool calling, code generation and software development, multi-turn conversations with extended context, multilingual content generation.
Qwen3-VL-235B-A22B Understands images and video. Extracts text from documents, converts screenshots to working code, and automates clicking through interfaces. Extracting text from images and PDFs, converting UI designs or screenshots to working code, automating clicks and navigation in applications, video analysis and understanding, reading charts and diagrams.

When implementing publicly available models, give careful consideration to data privacy requirements in your production environments, check for bias in output, and monitor your results for data security, responsible AI, and model evaluation.

You can access the enterprise-grade security features of Amazon Bedrock and implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. You can also evaluate and compare models to identify the optimal models for your use cases by using Amazon Bedrock model evaluation tools.

To get started, you can quickly test these models with a few prompts in the playground of the Amazon Bedrock console or use any AWS SDKs to include access to the Bedrock InvokeModel and Converse APIs. You can also use these models with any agentic framework that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore and Strands Agents. To learn more, visit Code examples for Amazon Bedrock using AWS SDKs in the Amazon Bedrock User Guide.

Now available
Check the full Region list for availability and future updates of new models or search your model name in the AWS CloudFormation resources tab of AWS Capabilities by Region. To learn more, check out the Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give these models a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Introducing Amazon EC2 X8aedz instances powered by 5th Gen AMD EPYC processors for memory-intensive workloads

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-amazon-ec2-x8aedz-instances-powered-by-5th-gen-amd-epyc-processors-for-memory-intensive-workloads/

Today, we’re announcing the availability of new memory-optimized, high-frequency Amazon Elastic Compute Cloud (Amazon EC2) X8aedz instances powered by a 5th Gen AMD EPYC processor. These instances offer the highest CPU frequency, 5GHz in the cloud. They deliver up to two times higher compute performance and 31% price-performance compared to previous generation X2iezn instances.

X8aedz instances are ideal for electronic design automation (EDA) workloads, such as physical layout and physical verification jobs, and relational databases that benefit from high single-threaded processor performance and a large memory footprint. The combination of 5 GHz processors and local NVMe storage enables faster processing of memory-intensive backend EDA workloads such as floor planning, logic placement, clock tree synthesis (CTS), routing, and power/signal integrity analysis. The high memory-to-vCPU ratio of 32:1 makes these instances particularly effective for applications with vCPU-based licensing models.

Let me explain the instance type naming: The “a” suffix indicates an AMD processor, “e” denotes extended memory in the memory-optimized instance family, “d” represents local NVMe-based SSDs physically connected to the host server, and “z” indicates high-frequency processors.

X8aedz instances
X8aedz instances are available in eight sizes ranging from 2–96 vCPUs with 64–3,072 GiB of memory, including two bare metal sizes. X8aedz instances feature up to 75 Gbps of network bandwidth with support for the Elastic Fabric Adapter (EFA), up to 60 Gbps of throughput to the Amazon Elastic Block Store (Amazon EBS), and up to 8 TB of local NVMe SSD storage.

Here are the specs for X8aedz instances:

Instance name vCPUs Memory
(GiB)
NVMe SSD storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
x8aedz.large 2 64 158 Up to 18.75 Up to 15
x8aedz.xlarge 4 128 316 Up to 18.75 Up to 15
x8aedz.3xlarge 12 384 950 Up to 18.75 Up to 15
x8aedz.6xlarge 24 768 1,900 18.75 15
x8aedz.12xlarge 48 1,536 3,800 37.5 30
x8aedz.24xlarge 96 3,072 7,600 75 60
x8aedz.metal-12xl 48 1,536 3,800 37.5 30
x8aedz.metal-24xl 96 3,072 7,600 75 60

With the 60 Gbps Amazon EBS bandwidth and up to 8 TB of local NVMe SSD storage, you can achieve faster database response times and reduced latency for EDA operations, ultimately accelerating time-to-market for chip designs. These instances also support the instance bandwidth configuration feature that offers flexibility in allocating resources between network and EBS bandwidth. You can scale network or EBS bandwidth by 25% and improve database (read and write) performance, query processing, and logging speeds.

X8aedz instances use sixth-generation AWS Nitro cards, which offload CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

Now available
Amazon EC2 X8aedz instances are now available in US West (Oregon) and Asia Pacific (Tokyo) AWS Regions, and additional Regions will be coming soon. For Regional availability and future roadmap, search the instance type in the AWS CloudFormation resources tab of the AWS Capabilities by Region.

You can purchase these instances as On-Demand, Savings Plan, Spot Instances, and Dedicated Instances. To learn more, visit the Amazon EC2 Pricing page.

Give X8aedz instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 X8aedz instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS DevOps Agent helps you accelerate incident response and improve system reliability (preview)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-devops-agent-helps-you-accelerate-incident-response-and-improve-system-reliability-preview/

Today, we’re announcing the public preview of AWS DevOps Agent, a frontier agent that helps you respond to incidents, identify root causes, and prevent future issues through systematic analysis of past incidents and operational patterns.

Frontier agents represent a new class of AI agents that are autonomous, massively scalable, and work for hours or days without constant intervention.

When production incidents occur, on-call engineers face significant pressure to quickly identify root causes while managing stakeholder communications. They must analyze data across multiple monitoring tools, review recent deployments, and coordinate response teams. After service restoration, teams often lack bandwidth to transform incident learnings into systematic improvements.

AWS DevOps Agent is your always-on, autonomous on-call engineer. When issues arise, it automatically correlates data across your operational toolchain, from metrics and logs to recent code deployments in GitHub or GitLab. It identifies probable root causes and recommends targeted mitigations, helping reduce mean time to resolution. The agent also manages incident coordination, using Slack channels for stakeholder updates and maintaining detailed investigation timelines.

To get started, you connect AWS DevOps Agent to your existing tools through the AWS Management Console. The agent works with popular services such as Amazon CloudWatch, Datadog, Dynatrace, New Relic, and Splunk for observability data, while integrating with GitHub Actions and GitLab CI/CD to track deployments and their impact on your cloud resources. Through the bring your own (BYO) Model Context Protocol (MCP) server capability, you can also integrate additional tools such as your organization’s custom tools, specialized platforms or open source observability solutions, such as Grafana and Prometheus into your investigations.

The agent acts as a virtual team member and can be configured to automatically respond to incidents from your ticketing systems. It includes built-in support for ServiceNow, and through configurable webhooks, can respond to events from other incident management tools like PagerDuty. As investigations progress, the agent updates tickets and relevant Slack channels with its findings. All of this is powered by an intelligent application topology the agent builds—a comprehensive map of your system components and their interactions, including deployment history that helps identify potential deployment-related causes during investigations.

Let me show you how it works
To show you how it works, I deployed a straigthforward AWS Lambda function that intentionally generates errors when invoked. I deployed it in an AWS CloudFormation stack.

Step 1: Create an Agent Space

An Agent Space defines the scope of what AWS DevOps Agent can access as it performs tasks.

You can organize Agent Spaces based on your operational model. Some teams align an Agent Space with a single application, others create one per on-call team managing multiple services, and some organizations use a centralized approach. For this demonstration, I’ll show you how to create an Agent Space for a single application. This setup helps isolate investigations and resources for that specific application, making it easier to track and analyze incidents within its context.

In the AWS DevOps Agent section of the AWS Management Console, I select Create Agent Space, enter a name for this space and create the AWS Identity and Access Management (IAM) roles it uses to introspect AWS resources in my or others’ AWS accounts.

AWS DevOps Agent - Create an Agent SpaceFor this demo, I choose to enable the AWS DevOps Agent web app; more about this later. This can be done at a later stage.

When ready, I choose Create.

AWS DevOps Agent - Enable Web AppAfter it has been created, I choose the Topology tab.

This view shows the key resources, entities, and relationships AWS DevOps Agent has selected as a foundation for performing its tasks efficiently. It doesn’t represent everything AWS DevOps Agent can access or see, only what the Agent considers most relevant right now. By default, the Topology includes the AWS resources that are contained in my account. As your agent completes more tasks, it will discover and add new resources to this list.

AWS DevOps Agent - Topology

Step 2: Configure the AWS DevOps web app for the operators

The AWS DevOps Agent web app provides a web interface for on-call engineers to manually trigger investigations, view investigation details including relevant topology elements, steer investigations, and ask questions about an investigation.

I can access the web app directly from my Agent Space in the AWS console by choosing the Operator access link. Alternatively, I can use AWS IAM Identity Center to configure user access for my team. IAM Identity Center lets me manage users and groups directly or connect to an identity provider (IdP), providing a centralized way to control who can access the AWS DevOps Agent web app.

AWS DevOps Agent - web app access

At this stage, I have an Agent Space all set up to focus investigations and resources for this specific application, and I’ve enabled the DevOps team to initiate investigations using the web app.

Now that the one-time setup for this application is done, I start invoking the faulty Lambda function. It generates errors at each invocation. The CloudWatch alarm associated with the Lambda errors count turns on to ALARM state. In real life, you might receive an alert from external services, such as ServiceNow. You can configure AWS DevOps Agent to automatically start investigations when receiving such alerts.

For this demo, I manually start the investigation by selecting Start Investigation.

You can also choose from several preconfigured starting points to quickly begin your investigation: Latest alarm to investigate your most recent triggered alarm and analyze the underlying metrics and logs to determine the root cause, High CPU usage to investigate high CPU utilization metrics across your compute resources and identify which processes or services are consuming excessive resources, or Error rate spike to investigate the recent increase in application error rates by analyzing metrics, application logs, and identifying the source of failures.

AWS DevOps Agent - web app

I enter some information, such as Investigation details, Investigation starting point, the Date and time of the incident, the AWS Account ID for the incident.

- web app - start investigation

In the AWS DevOps Agent web app, you can watch the investigation unfold in real time. The agent identifies the application stack. It correlates metrics from CloudWatch, examines logs from CloudWatch Logs or external sources, such as Splunk, reviews recent code changes from GitHub, and analyzes traces from AWS X-Ray.

- web app - application stack

It identifies the error patterns and provides a detailed investigation summary. In the context of this demo, the investigation reveals that these are intentional test exceptions, shows the timeline of function invocations leading to the alarm, and even suggests monitoring improvements for error handling.

The agent uses a dedicated incident channel in Slack, notifies on-call teams if needed, and provides real-time status updates to stakeholders. Through the investigation chat interface, you can interact directly with the agent by asking clarifying questions such as “which logs did you analyze?” or steering the investigation by providing additional context, such as “focus on these specific log groups and rerun your analysis.” If you need expert assistance, you can create an AWS Support case with a single click, automatically populating it with the agent’s findings, and engage with AWS Support experts directly through the investigation chat window.

For this demo, the AWS DevOps Agent correctly identified manual activities in the Lambda console to invoke a function that intentionally triggers errors 😇.

- web app - root cause

Beyond incident response, AWS DevOps Agent analyzes my recent incidents to identify high-impact improvements that prevent future issues.

During active incidents, the agent offers immediate mitigation plans through its incident mitigations tab to help restore service quickly. Mitigation plans consist of specs that provide detailed implementation guidance for developers and agentic development tools like Kiro.

For longer-term resilience, it identifies potential enhancements by examining gaps in observability, infrastructure configurations, and deployment pipeline. My straightforward demo that triggered intentional errors was not enough to generate relevant recommendations though.

AWS DevOps Agent - web app - recommendations

For example, it might detect that a critical service lacks multi-AZ deployment and comprehensive monitoring. The agent then creates detailed recommendations with implementation guidance, considering factors like operational impact and implementation complexity. In an upcoming quick follow-up release, the agent will expand its analysis to include code bugs and testing coverage improvements.

Availability
You can try AWS DevOps Agent today in the US East (N. Virginia) Region. Although the agent itself runs in US East (N. Virginia) (us-east-1), it can monitor applications deployed in any Region, across multiple AWS accounts.

During the preview period, you can use AWS DevOps Agent at no charge, but there will be a limit on the number of agent task hours per month.

As someone who has spent countless nights debugging production issues, I’m particularly excited about how AWS DevOps Agent combines deep operational insights with practical, actionable recommendations. The service helps teams move from reactive firefighting to proactive system improvement.

To learn more and sign up for the preview, visit AWS DevOps Agent. I look forward to hearing how AWS DevOps Agent helps improve your operational efficiency.

— seb

Accelerate AI development using Amazon SageMaker AI with serverless MLflow

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/accelerate-ai-development-using-amazon-sagemaker-ai-with-serverless-mlflow/

Since we announced Amazon SageMaker AI with MLflow in June 2024, our customers have been using MLflow tracking servers to manage their machine learning (ML) and AI experimentation workflows. Building on this foundation, we’re continuing to evolve the MLflow experience to make experimentation even more accessible.

Today, I’m excited to announce that Amazon SageMaker AI with MLflow now includes a serverless capability that eliminates infrastructure management. This new MLflow capability transforms experiment tracking into an immediate, on-demand experience with automatic scaling that removes the need for capacity planning.

The shift to zero-infrastructure management fundamentally changes how teams approach AI experimentation—ideas can be tested immediately without infrastructure planning, enabling more iterative and exploratory development workflows.

Getting started with Amazon SageMaker AI and MLflow
Let me walk you through creating your first serverless MLflow instance.

I navigate to Amazon SageMaker AI Studio console and select the MLflow application. The term MLflow Apps replaces the previous MLflow tracking servers terminology, reflecting the simplified, application-focused approach.

Here, I can see there’s already a default MLflow App created. This simplified MLflow experience makes it more straightforward for me to start doing experiments.

I choose Create MLflow App, and enter a name. Here, I have both an AWS Identity and Access Management (IAM) role and Amazon Simple Service (Amazon S3) bucket are already been configured. I only need to modify them in Advanced settings if needed.

Here’s where the first major improvement becomes apparent—the creation process completes in approximately 2 minutes. This immediate availability enables rapid experimentation without infrastructure planning delays, eliminating the wait time that previously interrupted experimentation workflows.

After it’s created, I receive an MLflow Amazon Resource Name (ARN) for connecting from notebooks. The simplified management means no server sizing decisions or capacity planning required. I no longer need to choose between different configurations or manage infrastructure capacity, which means I can focus entirely on experimentation. You can learn how to use MLflow SDK at Integrate MLflow with your environment in the Amazon SageMaker Developer Guide.

With MLflow 3.4 support, I can now access new capabilities for generative AI development. MLflow Tracing captures detailed execution paths, inputs, outputs, and metadata throughout the development lifecycle, enabling efficient debugging across distributed AI systems.

This new capability also introduces cross-domain access and cross-account access through AWS Resource Access Manager (AWS RAM) share. This enhanced collaboration means that teams across different AWS domains and accounts can share MLflow instances securely, breaking down organizational silos.

Better together: Pipelines integration
Amazon SageMaker Pipelines is integrated with MLflow. SageMaker Pipelines is a serverless workflow orchestration service purpose-built for machine learning operations (MLOps) and large language model operations (LLMOps) automation—the practices of deploying, monitoring, and managing ML and LLM models in production. You can easily build, execute, and monitor repeatable end-to-end AI workflows with an intuitive drag-and-drop UI or the Python SDK.

From a pipeline, a default MLflow App will be created if one doesn’t already exist. The experiment name can be defined and metrics, parameters, and artifacts are logged to the MLflow App as defined in your code. SageMaker AI with MLflow is also integrated with familiar SageMaker AI model development capabilities like SageMaker AI JumpStart and Model Registry, enabling end-to-end workflow automation from data preparation through model fine-tuning.

Things to know
Here are key points to note:

  • Pricing – The new serverless MLflow capability is offered at no additional cost. Note there are service limits that apply.
  • Availability – This capability is available in the following AWS Regions: US East (N. Virginia, Ohio), US West (N.California, Oregon), Asia Pacific (Mumbai, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Paris, Stockholm), South America (São Paulo).
  • Automatic upgrades: MLflow in-place version upgrades happen automatically, providing access to the latest features without manual migration work or compatibility concerns. The service currently supports MLflow 3.4, providing access to the latest capabilities including enhanced tracing features.
  • Migration support – You can use the open source MLflow export-import tool available at mlflow-export-import to help migrate from existing Tracking Servers, whether they’re from SageMaker AI, self-hosted, or otherwise to serverless MLflow (MLflow Apps).

Get started with serverless MLflow by visiting Amazon SageMaker AI Studio and creating your first MLflow App. Serverless MLflow is also supported in SageMaker Unified Studio for additional workflow flexibility.

Happy experimenting!
— Donnie

Introducing Amazon Nova 2 Lite, a fast, cost-effective reasoning model

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-amazon-nova-2-lite-a-fast-cost-effective-reasoning-model/

Today, we’re releasing Amazon Nova 2 Lite, a fast, cost-effective reasoning model for everyday workloads. Available in Amazon Bedrock, the model offers industry-leading price performance and helps enterprises and developers build capable, reliable, and efficient agentic-AI applications. For organizations who need AI that truly understands their domain, Nova 2 Lite is the best model to use with Nova Forge to build their own frontier intelligence.

Nova 2 Lite supports extended thinking, including step-by-step reasoning and task decomposition, before providing a response or taking action. Extended thinking is off by default to deliver fast, cost-optimized responses, but when deeper analysis is needed, you can turn it on and choose from three thinking budget levels: low, medium, or high, giving you control over the speed, intelligence, and cost tradeoff.

Nova 2 Lite supports text, image, video, document as input and offers a one million-token context window, enabling expanded reasoning and richer in-context learning. In addition, Nova 2 Lite can be customized for your specific business needs. The model also includes access to two built-in tools: web grounding and a code interpreter. Web grounding retrieves publicly available information with citations, while the code interpreter allows the model to run and evaluate code within the same workflow.

Amazon Nova 2 Lite demonstrates strong performance across diverse evaluation benchmarks. The model excels in core intelligence across multiple domains including instruction following, math, and video understanding with temporal reasoning. For agentic workflows, Nova 2 Lite shows reliable function calling for task automation and precise UI interaction capabilities. The model also demonstrates strong code generation and practical software engineering problem-solving abilities.

Amazon Nova 2 Lite benchmarks

Nova 2 Lite is built to meet your company’s needs
Nova 2 Lite can be used for a broad range of your everyday AI tasks. It offers the best combination of price, performance, and speed. Early customers are using Nova 2 Lite for customer service chatbots, document processing, and business process automation.

Nova 2 Lite can help support workloads across many different use cases:

  • Business applications – Automate business process workflow, intelligent document processing (IDP), customer support, and web search to improve productivity and outcomes
  • Software engineering – Generate code, debugging, refactoring, and migrating systems to accelerate development and increase efficiency
  • Business intelligence and research – Use long-horizon reasoning and web grounding to analyze internal and external sources to uncover insights, and make informed decisions

For specific requirements, Nova 2 Lite is also available for customization on both Amazon Bedrock and Amazon SageMaker AI.

Using Amazon Nova 2 Lite
In the Amazon Bedrock console, you can use the Chat/Text playground to quickly test the new model with your prompts. To integrate the model into your applications, you can use any AWS SDKs with the Amazon Bedrock InvokeModel and Converse API. Here’s a sample invocation using the AWS SDK for Python (Boto3).

import boto3

AWS_REGION="us-east-1"
MODEL_ID="global.amazon.nova-2-lite-v1:0"
MAX_REASONING_EFFORT="low" # low, medium, high

bedrock_runtime = boto3.client("bedrock-runtime", region_name=AWS_REGION)

# Enable extended thinking for complex problem-solving
response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=[{
        "role": "user",
        "content": [{"text": "I need to optimize a logistics network with 5 warehouses, 12 distribution centers, and 200 retail locations. The goal is to minimize total transportation costs while ensuring no location is more than 50 miles from a distribution center. What approach should I take?"}]
    }],
    additionalModelRequestFields={
        "reasoningConfig": {
            "type": "enabled", # enabled, disabled (default)
            "maxReasoningEffort": MAX_REASONING_EFFORT
        }
    }
)

# The response will contain reasoning blocks followed by the final answer
for block in response["output"]["message"]["content"]:
    if "reasoningContent" in block:
        reasoning_text = block["reasoningContent"]["reasoningText"]["text"]
        print(f"Nova's thinking process:\n{reasoning_text}\n")
    elif "text" in block:
        print(f"Final recommendation:\n{block['text']}")

You can also use the new model with agentic frameworks that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore. In this way, you can build agents for a broad range of tasks. Here’s the sample code for an interactive multi-agent system using the Strands Agents SDK. The agents have access to multiple tools, including read and write file access and the possibility to run shell commands.

from strands import Agent
from strands.models import BedrockModel
from strands_tools import calculator, editor, file_read, file_write, shell, http_request, graph, swarm, use_agent, think

AWS_REGION="us-east-1"
MODEL_ID="global.amazon.nova-2-lite-v1:0"
MAX_REASONING_EFFORT="low" # low, medium, high

SYSTEM_PROMPT = (
    "You are a helpful assistant. "
    "Follow the instructions from the user. "
    "To help you with your tasks, you can dynamically create specialized agents and orchestrate complex workflows."
)

bedrock_model = BedrockModel(
    region_name=AWS_REGION,
    model_id=MODEL_ID,
    additional_request_fields={
        "reasoningConfig": {
            "type": "enabled", # enabled, disabled (default)
            "maxReasoningEffort": MAX_REASONING_EFFORT
        }
    }
)

agent = Agent(
    model=bedrock_model,
    system_prompt=SYSTEM_PROMPT,
    tools=[calculator, editor, file_read, file_write, shell, http_request, graph, swarm, use_agent, think]
)

while True:
    try:
        prompt = input("\nEnter your question (or 'quit' to exit): ").strip()
        if prompt.lower() in ['quit', 'exit', 'q']:
            break
        if len(prompt) > 0:
            agent(prompt)
    except KeyboardInterrupt:
        break
    except EOFError:
        break

print("\nGoodbye!")

Things to know
Amazon Nova 2 Lite is now available in Amazon Bedrock via global cross-Region inference in multiple locations. For Regional availability and future roadmap, visit AWS Capabilities by Region.

Nova 2 Lite includes built-in safety controls to promote responsible AI use, with content moderation capabilities that help maintain appropriate outputs across a wide range of applications.

To understand the costs, see Amazon Bedrock pricing. To learn more, visit the Amazon Nova User Guide.

Start building with Nova 2 Lite today. To experiment with the new model, visit the Amazon Nova interactive website. Try the model in the Amazon Bedrock console, and share your feedback on AWS re:Post.

— Danilo
New AWS Security Agent secures applications proactively from design to deployment (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/new-aws-security-agent-secures-applications-proactively-from-design-to-deployment-preview/

Today, we’re announcing AWS Security Agent in preview, a frontier agent that proactively secures your applications throughout the development lifecycle. It conducts automated application security reviews tailored to your organizational requirements and delivers context-aware penetration testing on demand. By continuously validating application security from design to deployment, it helps prevent vulnerabilities early in development.

Static application security testing (SAST) tools examine code without runtime context, whereas dynamic application security testing (DAST) tools assess running applications without application-level context. Both types of tools are one-dimensional because they don’t understand your application context. They don’t understand how your application is designed, what security threats it faces, and where and how it runs. This forces security teams to manually review everything, creating delays. Penetration testing is even slower—you either wait weeks for an external vendor or your internal security team to find time. When every application requires a manual security review and penetration test, the backlog grows quickly. Applications wait weeks or months for security validation before they can launch. This creates a gap between the frequency of software releases and the frequency of security evaluations. Security is not applied to the entire portfolio of applications, leaving customers exposed and knowingly shipping vulnerable code to meet deadlines. Over 60 percent of organizations update web applications weekly or more often, while nearly 75 percent test web applications monthly or less often. A 2025 report from Checkmarx found that 81 percent of organizations knowingly deploy vulnerable code to meet delivery deadlines.

AWS Security Agent is context-aware—it understands your entire application. It understands your application design, your code, and your specific security requirements. It continuously scans for security violations automatically and runs penetration tests on-demand instantly without scheduling. The penetration testing agent creates a customized attack plan informed by the context it has learned from your security requirements, design documents, and source code, and dynamically adapts as it runs based on what it discovers, such as endpoints, status and error codes, and credentials. This helps surface deeper, more sophisticated vulnerabilities before production, ensuring your application is secure before it launches without delays or surprises.

“SmugMug is excited to add AWS Security Agent to our automated security portfolio. AWS Security Agent transforms our security ROI by enabling pen test assessments that complete in hours rather than days, at a fraction of manual testing costs. We can now assess our services more frequently, dramatically decreasing the time to identify and address issues earlier in the software development lifecycle.” says Erik Giberti, Sr. Director of Product Engineering at SmugMug.

Get started with AWS Security Agent
AWS Security Agent provides design security review, code security review, and on-demand penetration testing capabilities. Design and code review check organizational security requirements that you define, and penetration testing learns application context from source code and specifications to identify vulnerabilities. To get started, navigate to the AWS Security Agent console. The console landing page provides an overview of how AWS Security Agent delivers continuous security assessment across your development lifecycle.

The Get started with AWS Security Agent panel on the right side of the landing page guides you through initial configuration. Choose Set up AWS Security Agent to create your first agent space and begin performing security reviews on your applications.

Provide an Agent space name to identify which agent you’re interacting with across different security assessments. An agent space is an organizational container that represents a distinct application or project you want to secure. Each agent space has its own testing scope, security configuration, and dedicated web application domain. We recommend creating one agent space per application or project to maintain clear boundaries and organized security assessments. You can optionally add a Description to provide context about the agent space’s purpose for other administrators.

When you create the first agent space in the AWS Management Console, AWS creates the Security Agent Web Application. The Security Agent Web Application is where users conduct design reviews and execute penetration tests within the boundaries established by administrators in the console. Users select which agent space to work in when conducting design reviews or executing penetration tests.

During the setup process, AWS Security Agent offers two options for managing user access to the Security Agent Web Application: Single Sign-On (SSO) with IAM Identity Center, which enables team-wide SSO access by integrating with AWS IAM Identity Center, or IAM users, which allows only AWS Identity and Access Management (IAM) users of this AWS account to access the Security Agent Web Application directly through the console and is best for quick setup or access without SSO configuration. When you choose the SSO option, AWS Security Agent creates an IAM Identity Center instance to provide centralized authentication and user management for AppSec team members who will access design reviews, code reviews, and penetration testing capabilities through the Security Agent Web Application.

The permissions configuration section helps you control how AWS Security Agent accesses other AWS services, APIs, and accounts. You can create a default IAM role that AWS Security Agent will use to access resources, or choose an existing role with appropriate permissions.

After completing the initial configuration, choose Set up AWS Security Agent to create the agent.

After creating an agent space, the agent configuration page displays three capability cards: Design review, Code review, and Penetration testing. While not required to operate the penetration testing, if you plan to use design review or code review capabilities, you can configure which security requirements will guide those assessments. AWS Security Agent includes AWS managed requirements, and you can optionally define custom requirements tailored to your organization. You can also manage which team members have access to the agent.

Security requirements
AWS Security Agent enforces organizational security requirements that you define so that applications comply with your team’s policies and standards. Security requirements specify the controls and policies that your applications must follow during both design and code review phases.

To manage security requirements, navigate to Security requirements in the navigation pane. These requirements are shared across all agent spaces and apply to both design and code reviews.

Managed security requirements are based on industry standards and best practices. These requirements are ready to use, maintained by AWS, and you can enable them instantly without configuration.

When creating a custom security requirement, you specify the control name and description that defines the policy. For example, you might create a requirement called Network Segmentation Strategy Defined that requires designs to define clear network segmentation separating workload components into logical layers based on data sensitivity. Or you might define Short Session Timeouts for Privileged and PII Access to mandate specific timeout durations for administrative and personally identifiable information (PII) access. Another example is Customer-Managed Encryption Keys Required, which requires designs to specify customer managed AWS Key Management Service (AWS KMS) keys rather than AWS managed keys for encrypting sensitive data at rest. AWS Security Agent evaluates designs and code against these enabled requirements, identifying policy violations.

Design security review
The design review capability analyzes architectural documents and product specifications to identify security risks before code is written. AppSec teams upload design documents through the AWS Security Agent console or ingest them from S3 and other connected services. AWS Security Agent assesses compliance with organizational security requirements and provides remediation guidance.

Before conducting design reviews, confirm you’ve configured the security requirements that AWS Security Agent will check. You can get started with AWS managed security requirements or define custom requirements tailored to your organization, as described in the Security requirements section.

To get started with the Design review, choose Admin access under Web app access to access the web app interface. When logged in, choose Create design review. Enter a Design review name to identify the assessment—for example, when assessing a new feature design that extends your application—and upload up to five design files. Choose Start design review to begin the assessment against your enabled security requirements.

After completing a design review, the design review detail page displays the review status, completion date, and files reviewed in the Details section. The Findings summary shows the count of findings across four compliance status categories:

  • Non-compliant – The design violates or inadequately addresses the security requirement.
  • Insufficient data – The uploaded files don’t contain enough information to determine compliance.
  • Compliant – The design meets the security requirement based on the uploaded documentation.
  • Not applicable – The security requirement’s relevance criteria indicate it doesn’t apply to this system design.

The Findings summary section helps you quickly assess which security requirements need attention. Non-compliant findings require updates to your design documents, while Insufficient data findings indicate gaps in the documentation where security teams should work with application teams to gather additional clarity before AWS Security Agent can complete the assessment.

The Files reviewed section displays all uploaded documents with options to search and download the original files.

The Review findings section lists each security requirement evaluated during the review along with its compliance status. In this example, the findings include Network Segmentation Strategy Defined, Customer-Managed Encryption Keys Required, and Short Session Timeouts for Privileged and PII Access. These are the custom security requirements defined earlier in the Security requirements section. You can search for specific security requirements or filter findings by compliance status to focus on items that require action.

When you choose a specific finding, AWS Security Agent displays detailed justification explaining the compliance status and provides recommended remediation steps. This context-aware analysis helps you understand security concerns specific to your design rather than generic security guidance. For designs with noncompliant findings, you can update your documentation to address the security requirements and create a new design review to validate the improvements. You can also choose Clone this design review to create a new assessment based on the current configuration or choose Download report to export the complete findings for sharing with your team.

After validating that your application design meets organizational security requirements, the next step is enforcing those same requirements as developers write code.

Code security review
The code review capability analyzes pull requests in GitHub to identify security vulnerabilities and organizational policy violations. AWS Security Agent detects OWASP Top Ten common vulnerabilities such as SQL injection, cross-site scripting, and inadequate input validation. It also enforces the same organizational security requirements used in design review, implementing code compliance with your team’s policies beyond common vulnerabilities.

When your application checks in new code, AWS Security Agent verifies compliance with organizational security requirements that go beyond common vulnerabilities. For example, if your organization requires audit logs to be retained for only 90 days, AWS Security Agent identifies when code configures a 365-day retention period and comments on the pull request with the specific violation. This catches policy violations that traditional security tools miss because the code is technically functional and secure.

To enable code review, choose Enable code review on the agent configuration page and connect your GitHub repositories. You can enable code review for specific repositories or connect repositories without enabling code review if you want to use them for penetration testing context instead.

For detailed setup instructions, visit the AWS Security Agent documentation.

On-demand penetration testing
The on-demand penetration testing capability executes comprehensive security testing to discover and validate vulnerabilities through multistep attack scenarios. AWS Security Agent systematically discovers the application’s attack surface through reconnaissance and endpoint enumeration, then deploys specialized agents to execute security testing across 13 risk categories, including authentication, authorization, and injection attacks. When provided source code, API specifications, and business documentation, AWS Security Agent builds deeper context about the application’s architecture and business rules to generate more targeted test cases. It adapts testing based on application responses and adjusts attack strategies as it discovers new information during the assessment.

AWS Security Agent tests web applications and APIs against OWASP Top Ten vulnerability types, identifying exploitable issues that static analysis tools miss. For example, while dynamic application security testing (DAST) tools look for direct server-side template injection (SSTI) payloads, AWS Security Agent can combine SSTI attacks with error forcing and debug output analysis to execute more complex exploits. AppSec teams define their testing scope—target URLs, authentication details, threat models, and documentation—the same as they would brief a human penetration tester. Using this understanding, AWS Security Agent develops application context and autonomously executes sophisticated attack chains to discover and validate vulnerabilities. This transforms penetration testing from a periodic bottleneck into a continuous security practice, reducing risk exposure.

To enable penetration testing, choose Enable penetration test on the agent configuration page. You can configure target domains, VPC settings for private endpoints, authentication credentials, and additional context sources such as GitHub repositories or S3 buckets. You must verify ownership of each domain before AWS Security Agent can run penetration testing.

After enabling the capability, create and run penetration tests through the AWS Security Agent Web Application. For detailed setup and configuration instructions, visit the AWS Security Agent documentation.

After creating and running a penetration test, the detail page provides an overview of test execution and results. You can run new tests or modify the configuration from this page. The page displays information about the most recent execution, including start time, status, duration, and a summary of discovered vulnerabilities categorized by severity. You can also view a history of all previous test runs with their findings summaries.

For each run, the detail page provides three tabs. The Penetration test run overview tab displays high-level information about the execution, including duration and overall status. The Penetration test logs tab lists all tasks executed during the penetration test, providing visibility into how AWS Security Agent discovered vulnerabilities, including the security testing actions performed, application responses, and the reasoning behind each test. The Findings tab displays all discovered vulnerabilities with complete details, including descriptions, attack reasoning, steps to reproduce, impact, and remediation guidance.

Join the preview
To get started with AWS Security Agent, visit the AWS Security Agent console and create your first agent to begin automating design reviews, code reviews, and penetration testing across your development lifecycle. During the preview period, AWS Security Agent is free of charge.

AWS Security Agent is available in the US East (N. Virginia) Region.

To learn more, visit the AWS Security Agent product page and technical documentation.

— Esra

AWS Security Hub now generally available with near real-time analytics and risk prioritization

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-security-hub-now-generally-available-with-near-real-time-analytics-and-risk-prioritization/

Today, AWS Security Hub is generally available, transforming how security teams identify and respond to critical security risks across their AWS environments. These new capabilities were first announced in preview at AWS re:Inforce 2025. Security Hub prioritizes your critical security issues and unifies your security operations to help you respond at scale by correlating and enriching signals across multiple AWS security services. Security Hub provides near real-time risk analytics, trends, unified enablement, streamlined pricing, and automated correlation that transforms security signals into actionable insights.

Organizations deploying multiple security tools need to manually correlate signals across different consoles, creating operational overhead that can delay detection and response times. Security teams use various tools for threat detection, vulnerability management, security posture monitoring, and sensitive data discovery, but extracting value from the findings these tools generate requires significant manual effort to understand relationships and determine priority.

Security Hub addresses these challenges through built-in integration that unifies your cloud security operations. Available for individual accounts or entire AWS Organizations accounts, Security Hub automatically aggregates and correlates signals from Amazon GuardDuty, Amazon Inspector, AWS Security Hub Cloud Security Posture Management (AWS Security Hub CSPM), and Amazon Macie, organizing them by threats, exposures, resources, and security coverage. This unified approach reduces manual correlation work, helping you quickly identify critical issues, understand coverage gaps, and prioritize remediation based on severity and impact.

What’s new in general availability
Since the preview announcement, Security Hub has added several new features.

Historical trends
Security Hub includes a Trends feature through the Summary dashboard that provides up to 1 year of historical data for findings and resources across your organization. The Summary dashboard displays an overview of your exposures, threats, resources, and security coverage through customizable widgets that you can add, remove, and arrange based on your operational needs.

The dashboard includes a Trends overview widget that displays period-over-period analysis for day-over-day, week-over-week, and month-over-month comparisons, helping you track whether your security posture is improving or degrading. Trend widgets for Active threat findings, Active exposure findings, and Resource trends provide visualizations of average counts over selectable time periods including 5 days, 30 days, 90 days, 6 months, and 1 year. You can filter these visualizations by severity levels such as critical, high, medium, and low, and hover over specific points in time to review detailed counts.

The Summary dashboard also includes widgets that display current exposure summaries prioritized by severity, threat summaries showing malicious or suspicious activity, and resource inventories organized by type and associated findings.

The Security coverage widget helps you identify gaps in your security service deployment across your organization. This widget tracks which AWS accounts and Regions have security services enabled, helping you understand where you might lack visibility into threats, vulnerabilities, misconfigurations, or sensitive data. The widget displays account coverage across security capabilities including vulnerability management by Amazon Inspector, threat detection by GuardDuty, sensitive data discovery by Amazon Macie, and posture management by AWS Security Hub CSPM. Coverage percentages show which security checks passed or failed across your AWS accounts and Regions where Security Hub is enabled.

You can apply filters to widgets using shared filters that apply across all widgets, finding filters for exposure and threat data, or resource filters for inventory data. You can create and save filter sets using and/or operators to define specific criteria for your security analysis. Dashboard customizations, including saved filter sets and widget layouts, are saved automatically and persist across sessions.

If you configure cross-Region aggregation, the Summary dashboard includes findings from all linked Regions when viewing from your home Region. For delegated administrator accounts in AWS Organizations, data includes findings for both the administrator account and member accounts. Security Hub retains trends data for 1 year from the date findings are generated. After 1 year, trends data is automatically deleted.

Near real-time risk analytics
Security Hub now calculates exposures in near real-time and includes threat correlation from GuardDuty alongside existing vulnerability and misconfiguration analysis. When GuardDuty detects threats, Amazon Inspector identifies vulnerabilities, or AWS Security Hub CSPM discovers misconfigurations, Security Hub automatically correlates these findings and updates associated exposures. This advancement provides immediate feedback on your security posture, helping you quickly identify new exposures and verify that remediation actions have reduced risk as expected.

Security Hub correlates findings across AWS Security Hub CSPM, Amazon Inspector, Amazon Macie, Amazon GuardDuty, and other security services to identify exposures that could lead to security incidents. This correlation helps you understand when multiple security issues combine to create critical risk. Security Hub enriches security signals with context by analyzing resource associations, potential impact, and relationships between signals. For example, if Security Hub identifies an Amazon Simple Storage Service (Amazon S3) bucket containing sensitive data with versioning disabled, Object Lock disabled, and MFA delete disabled, remediating any component triggers automatic calculation, helping you verify remediation effectiveness without waiting for scheduled assessments.

The Exposure page organizes findings by title and severity, helping you focus on critical issues first. The page includes an Overview section with a trends graph that displays the average count of exposure findings over the last 90 days, segmented by severity level. This visualization helps you track changes in your exposure posture over time and identify patterns in security risk.

Exposure findings are grouped by title with expandable rows showing the count of affected resources and overall severity. Each exposure title describes the potential security impact, such as “Potential Data Destruction: S3 bucket with versioning, Object Lock, and MFA delete disabled” or “Potential Remote Execution: EC2 instance is reachable from VPC and has software vulnerabilities.” You can filter exposures using saved filter sets or quick filters based on severity levels including critical, high, medium, and low. The interface also provides filtering by account ID, resource type, and accounts, helping you quickly narrow down exposures relevant to specific parts of your infrastructure.

Security Hub generates exposures as soon as findings are available. For example, when you deploy an Amazon Elastic Compute Cloud (Amazon EC2) instance that is publicly accessible and Amazon Inspector detects a highly exploitable vulnerability while AWS Security Hub CSPM identifies the public accessibility configuration, Security Hub automatically correlates these findings to generate an exposure without waiting for a scheduled assessment. This near-real time correlation helps you identify critical risks in newly deployed resources and take action before they can be exploited.

When you select an exposure finding, the details page displays the exposure type, primary resource, Region, account, age, and creation time. The Overview section shows contributing traits that represent the security issues directly contributing to the exposure scenario. These traits are organized by categories such as Reachability, Vulnerability, Sensitive data, Misconfiguration, and Assumability.

The details page includes a Potential attack path tab that provides a visual graph showing how potential attackers could access and take control of your resources. This visualization displays the relationships between the primary resource (such as an EC2 instance), involved resources (such as VPC, subnet, network interface, security group, AWS Identity and Access Management (IAM) instance profile, IAM role, IAM policy, and volumes), and contributing traits. The graph helps you understand the complete attack surface and identify which security controls need adjustment.

The Traits tab lists all security issues contributing to the exposure, and the Resources tab shows all affected resources. The Remediation section provides prioritized guidance with links to documentation, recommending which traits to address first to reduce risk most effectively. By using this comprehensive view, you can investigate specific exposures, understand the full context of security risks, and track remediation progress as your team addresses vulnerabilities, misconfigurations, and other security gaps across your environment.

Expanded partner integrations
Security Hub supports integration with Jira and ServiceNow for incident management workflows. When viewing a finding, you can create a ticket in your preferred system directly from the AWS Security Hub console with finding details, severity, and recommended remediation steps automatically populated. You can also define automation rules in Security Hub that automatically create tickets in Atlassian’s Jira Service Management and ServiceNow based on criteria you specify, such as severity level, resource type, or finding type. This helps you route critical security issues to your incident response teams without manual intervention.

Security Hub findings are formatted in the Open Cybersecurity Schema Framework (OCSF) schema, an open-source standard that enables security tools to share data seamlessly. Partners who have built integrations with the OCSF format with Security Hub include Cribl, CrowdStrike, Databee, DataDog, Dynatrace, Expel, Graylog, Netskope, Securonix, SentinelOne, Splunk a Cisco company, Sumo Logic, Tines, Upwind Security, Varonis, DTEX, and Zscaler. Additionally, service partners such as Accenture, Caylent, Deloitte, Optiv, PwC, and Wipro can help you adopt Security Hub and the OCSF schema.

Security Hub also supports automated response workflows through Amazon EventBridge. You can create EventBridge rules that identify findings based on criteria you specify and route them to targets such as AWS Lambda functions or AWS Systems Manager Automation runbooks for processing and remediation. This helps you act on findings programmatically without manual intervention.

Now available
If you currently use AWS Security Hub CSPM, Amazon GuardDuty, Amazon Inspector, or Amazon Macie, you can access these capabilities by navigating to the AWS Security Hub console. If you’re a new customer, you can enable Security Hub through the AWS Management Console and configure the security services appropriate for your workloads. Security Hub automatically consumes findings from enabled services, making the findings available in the unified console and creating correlated exposure findings based on the ingested security data.

For Regional availability, visit our AWS Services by Region page. Near real-time exposure calculation and the Trends feature are included at no additional charge. Security Hub uses a streamlined, resource-based pricing model that consolidates charges across integrated AWS security services. The console includes a cost estimator to help you plan and forecast security investments across your AWS accounts and Regions before deployment. For detailed information about capabilities, supported integrations, and pricing, visit the AWS Security Hub product page and technical documentation.

— Esra

Amazon GuardDuty adds Extended Threat Detection for Amazon EC2 and Amazon ECS

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/amazon-guardduty-adds-extended-threat-detection-for-amazon-ec2-and-amazon-ecs/

Today, we’re announcing new enhancements to Amazon GuardDuty Extended Threat Detection with the addition of two attack sequence findings for Amazon Elastic Compute Cloud (Amazon EC2) instances and Amazon Elastic Container Service (Amazon ECS) tasks. These new findings build on the existing Extended Threat Detection capabilities, which already combine sequences involving AWS Identity and Access Management (IAM) credential misuse, unusual Amazon Simple Storage service (Amazon S3) bucket activity, and Amazon Elastic Kubernetes Service (Amazon EKS) cluster compromise. By adding coverage for EC2 instance groups and ECS clusters, this launch expands sequence-level visibility to virtual machine and container environments that support the same application. Together, these capabilities provide a more consistent and unified way to detect multistage activity across diverse Amazon Web Services (AWS) workloads.

Modern cloud environments are dynamic and distributed, often running virtual machines, containers, and serverless workloads at scale. Security teams strive to maintain visibility across these environments and connect related activities that might indicate complex, multistage attack sequences. These sequences can involve multiple steps, such as establishing initial access and persistence, providing missing credentials or performing unexpected data access, that unfold over time and across different sources. GuardDuty Extended Threat Detection automatically links these signals using AI and machine learning (ML) models trained at AWS scale to build a complete picture of the activity and surface high-confidence insights to help customers prioritize response actions. By combining evidence from diverse sources, this analysis produces high-fidelity, unified findings that would otherwise be difficult to infer from individual events.

How it works
Extended Threat Detection analyzes multiple types of security signals, including runtime activity, malware detections, VPC Flow Logs, DNS queries, and AWS CloudTrail events to identify patterns that represent a multistage attack across Amazon EC2 and Amazon ECS workloads. Detection works with the GuardDuty foundational plan, and turning on Runtime Monitoring for EC2 or ECS adds deeper process and network-level telemetry that strengthens signal analysis and increases the completeness of each attack sequence.

The new attack sequence findings combine runtime and other observed behaviors across the environment into a single critical-severity sequence. Each sequence includes an incident summary, a timeline of observed events, mapped MITRE ATT&CK® tactics and techniques, and remediation guidance to help you understand how the activity unfolded and which resources were affected.

EC2 instances and ECS tasks are often created and replaced automatically through Auto Scaling groups, shared launch templates, Amazon Machine Images (AMIs), IAM instance profiles, or cluster-level deployments. Because these resources commonly operate as part of the same application, activity observed across them might originate from a single underlying compromise. The new EC2 and ECS findings analyze these shared attributes and consolidate related signals into one sequence when GuardDuty detects a pattern affecting the group.

When a sequence is detected, the GuardDuty console highlights any critical-severity sequence findings on the Summary page, with the affected EC2 instance group or ECS cluster already identified. Selecting a finding opens a consolidated view that shows how the resources are connected, which signals contributed to the sequence, and how the activity progressed over time, helping you quickly understand the scope of impact across virtual machine and container workloads.

In addition to viewing sequences in the console, you can also see these findings in AWS Security Hub, where they appear on the new exposure dashboards alongside other GuardDuty findings to help you understand your overall security risk in one place. This detailed view establishes the context for interpreting how the analysis brings related signals together into a broader attack sequence.

Together, the analysis model and grouping logic give you a clearer, consolidated view of activity across virtual machine and container workloads, helping you focus on the events that matter instead of investigating numerous individual findings. By unifying related behaviors into a single sequence, Extended Threat Detection helps you assess the full context of an attack path and prioritize the most urgent remediation actions.

Now available
Amazon GuardDuty Extended Threat Detection with expanded coverage for EC2 instances and ECS tasks is now available in all AWS Regions where GuardDuty is offered. You can start using this capability today to detect coordinated, multistage activity across virtual machine and container workloads by combining signals from runtime activity, malware execution, and AWS API activity.

This expansion complements the existing Extended Threat Detection capabilities for Amazon EKS, providing unified visibility into coordinated, multistage activity across your AWS compute environment. To learn more, visit the Amazon GuardDuty product page.

–Betty

AWS Transform for mainframe introduces Reimagine capabilities and automated testing functionality

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-transform-for-mainframe-introduces-reimagine-capabilities-and-automated-testing-functionality/

In May, 2025, we launched AWS Transform for mainframe, the first agentic AI service for modernizing mainframe workloads at scale. The AI-powered mainframe agent accelerates mainframe modernization by automating complex, resource-intensive tasks across every phase of modernization—from initial assessment to final deployment. You can streamline the migration of legacy mainframe applications, including COBOL, CICS, DB2, and VSAM to modern cloud environments—cutting modernization timelines from years to months.

Today, we’re announcing enhanced capabilities in AWS Transform for mainframe that include AI-powered analysis features, support for the Reimagine modernization pattern, and testing automation. These enhancements solve two critical challenges in mainframe modernization: the need to completely transform applications rather than merely move them to the cloud, and the extensive time and expertise required for testing.

  • Reimagining mainframe modernization – This is a new AI-driven approach that completely reimagines the customer’s application architecture using modern patterns or moving from batch process to real-time functions. By combining the enhanced business logic extraction with new data lineage analysis and automated data dictionary generation from the legacy source code through AWS Transform, customers transform monolithic mainframe applications written in languages like COBOL into more modern architectural styles, like microservices.
  • Automated testing – Customers can use new automated test plan generation, test data collection scripts, and test case automation scripts. AWS Transform for mainframe also provides functional testing tools for data migration, results validation, and terminal connectivity. These AI-powered capabilities work together to accelerate testing timelines and improve accuracy through automation.

Let’s learn more about reimagining mainframe modernization and automated testing capabilities.

How to reimagine mainframe modernization
We recognize that mainframe modernization is not a one-size-fits-all proposition. Whereas tactical approaches focus on augmentation and maintaining existing systems, strategic modernization offers distinct paths: Replatform, Refactor, Replace, or the new Reimagine.

In the Reimagine pattern, AWS Transform AI-powered analysis combines mainframe system analysis with organizational knowledge to create detailed business and technical documentation and architecture recommendations. This helps preserve critical business logic while enabling modern cloud-native capabilities.

AWS Transform provides new advanced data analysis capabilities that are essential for successful mainframe modernization, including data lineage analysis and automated data dictionary generation. These features work together to define the structure and meaning to accompany the usage and relationships of mainframe data. Customers gain complete visibility into their data landscape, enabling informed decision-making for modernization. Their technical teams can confidently redesign data architectures while preserving critical business logic and relationships.

The Reimagining strategy follows the principle of human in the loop validation, which means that AI-generated application specifications and code such as AWS Transform and Kiro are continuously validated by domain experts. This collaborative approach between AI capabilities and human judgment significantly reduces transformation risk while maintaining the speed advantages of AI-powered modernization.

The pathway has a three-phase methodology to transform legacy mainframe applications into cloud-native microservices:

  • Reverse engineering to extract business logic and rules from existing COBOL or job control language (JCL) code using AWS Transform for mainframe.
  • Forward engineering to generate microservice specification, modernized source code, infrastructure as code (IaC), and modernized database.
  • Deploy and test to deploy the generated microservices to Amazon Web Services (AWS) using IaC and to test the functionality of the modernized application.

Although microservices architecture offers significant benefits for mainframe modernization, it’s crucial to understand that it’s not the best solution for every scenario. The choice of architectural patterns should be driven by the specific requirements and constraints of the system. The key is to select an architecture that aligns with both current needs and future aspirations, recognizing that architectural decisions can evolve over time as organizations mature their cloud-native capabilities.

The flexible approach supports both do-it-yourself and partner-led development, so you can use your preferred tools while maintaining the integrity of your business processes. You get the benefits of modern cloud architecture while preserving decades of business logic and reducing project risk.

Automated testing in action
The new automated testing feature supports IBM z/OS mainframe batch application stack at launch, which helps organizations address a wider range of modernization scenarios while maintaining consistent processes and tooling.

Here are the new mainframe capabilities:

  • Plan test cases – Create test plans from mainframe code, business logic, and scheduler plans.
  • Generate test data collection scripts – Create JCL scripts for data collection from your mainframe to your test plan.
  • Generate test automation scripts – Generate execution scripts to automate testing of modernized applications running in the target AWS environment.

To get started with automated testing, you should set up a workspace, assign a specific role to each user, and invite them to onboard your workspace. To learn more, visit Getting started with AWS Transform in the AWS Transform User Guide.

Choose Create job in your workspace. You can see all types of supported transformation jobs. For this example, I select the Mainframe Modernization job to modernize mainframe applications.

After a new job is created, you can kick off modernization for tests generation. This workflow is sequential and it is a place for you to answer the AI agent’s questions, providing the necessary input. You can add your collaborators and specify resource location where the codebase or documentation is located in your Amazon Simple Storage Service (Amazon S3) bucket.

I use a sample application for a credit card management system as the mainframe banking case with the presentation (BMS screens), business logic (COBOL) and data (VSAM/DB2), including online transaction processing and batch jobs.

After finishing the steps of analyzing code, extracting business logic, decomposing code, planning migration wave, you can experience new automated testing capabilities such as planning test cases, generating test data collection scripts, and test automation scripts.

The new testing workflow creates a test plan for your modernization project and generates test data collection scripts. You will have three planning steps:

  • Configure test plan inputs – You can link your test plan to your other job files. The test plan is generated based on analyzing the mainframe application code and can provide more details optionally using the extracted business logic, the technical documentation, the decomposition, and using a scheduler plan.
  • Define test plan scope – You can define the entry point, the specific program where the application’s execution flow begins. For example, the JCL for a batch job. In the test plan, each functional test case is designed to start the execution from a specific entry point.
  • Refine test plan – A test plan is made up of sequential test cases. You can reorder them, add new ones, merge multiple cases, or split one into two on the test case detail page. Batch test cases are composed of a sequence of JCLs following the scheduler plan.

Generating test data collection scripts collects test data from mainframe applications for functional equivalence testing. This step actively generates JCL scripts that will help you gather test data from the sample application’s various data sources (such as VSAM files or DB2 databases) for use in testing the modernized application. The step is designed to create automated scripts that can extract test data from VSAM datasets, query DB2 tables for sample data, collect sequential data sets, and generate data collection workflows. After this step is completed, you’ll have comprehensive test data collection scripts ready to use.

To learn more about automated testing, visit Modernization of mainframe applications in the AWS Transform User Guide.

Now available
The new capabilities in AWS Transform for mainframe are available today in all AWS Regions where AWS Transform for mainframe is offered. For Regional availability and future roadmap, visit the AWS Capabilities by Region. Currently, we offer our core features—including assessment and transformation—at no cost to AWS customers. To learn more, visit AWS Transform Pricing page.

Give it a try in the AWS Transform console. To learn more, visit the AWS Transform for mainframe product page and send feedback to AWS re:Post for AWS Transform for mainframe or through your usual AWS Support contacts.

— Channy

AWS Transform announces full-stack Windows modernization capabilities

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/aws-transform-announces-full-stack-windows-modernization-capabilities/

Earlier this year in May, we announced the general availability of AWS Transform for .NET, the first agentic AI service for modernizing .NET applications at scale. During the early adoption period of the service, we received valuable feedback indicating that, in addition to .NET application modernization, you would like to modernize SQL Server and legacy UI frameworks. Your applications typically follow a three-tier architecture—presentation tier, application tier, and database tier—and you need a comprehensive solution that can transform all of these tiers in a coordinated way.

Today, based on your feedback, we’re excited to announce AWS Transform for full-stack Windows modernization, to offload complex, tedious modernization work across the Windows application stack. You can now identify application and database dependencies and modernize them in an orchestrated way through a centralized experience.

AWS Transform accelerates full-stack Windows modernization by up to five times across application, UI, database, and deployment layers. Along with porting .NET Framework applications to cross-platform .NET, it migrates SQL Server databases to Amazon Aurora PostgreSQL-Compatible Edition with intelligent stored procedure conversion and dependent application code refactoring. For validation and testing, AWS Transform deploys applications to Amazon Elastic Compute Cloud (Amazon EC2) Linux or Amazon Elastic Container Service (Amazon ECS), and provides customizable AWS CloudFormation templates and deployment configurations for production use. AWS Transform has also added capabilities to modernize ASP.NET Web Forms UI to Blazor.

There is much to explore, so in this post I’ll provide the first look at AWS Transform for full-stack Windows modernization capabilities across all layers.

Create a full-stack Windows modernization transformation job
AWS Transform connects to your source code repositories and database servers, analyzes application and database dependencies, creates modernization waves, and orchestrates full-stack transformations for each wave.

To get started with AWS Transform, I first complete the onboarding steps outlined in the getting started with AWS Transform user guide. After onboarding, I sign in to the AWS Transform console using my credentials and create a job for full-stack Windows modernization.

Create a new job for Windows Modernization
Create a new job by choosing SQL Server Database Modernization

After creating the job, I complete the prerequisites. Then, I configure the database connector for AWS Transform to securely access SQL Server databases running on Amazon EC2 and Amazon Relational Database Service (Amazon RDS). The connector can connect to multiple databases within the same SQL Server instance.

Create new database connector by adding connector name and AWS Account ID

Next, I set up a connector to connect to my source code repositories.

Add a source code connector by adding Connection name, AWS Account ID and Code Connector Arn

Furthermore, I have the option to choose if I would like AWS Transform to deploy the transformed applications. I choose Yes and provide the target AWS account ID and AWS Region for deploying the applications. The deployment option can be configured later as well.

Choose if you would like to deploy transformed apps

After the connectors are set up, AWS Transform connects to the resources and runs the validation to verify IAM roles, network settings, and related AWS resources.

After the successful validation, AWS Transform discovers databases and their associated source code repositories. It identifies dependencies between databases and applications to create waves for transforming related components together. Based on this analysis, AWS Transform creates a wave-based transformation plan.

Start assessment for discovered database and source code repositories

Assessing database and dependent applications
For the assessment, I review the databases and source code repositories discovered by AWS Transform and choose the appropriate branches for code repositories. AWS Transform scans these databases and source code repositories, then presents a list of databases along with their dependent .NET applications and transformation complexity.

Start wave planning of asessed databases and dependent repositories

I choose the target databases and repositories for modernization. AWS Transform analyzes these selections and generates a comprehensive SQL Modernization Assessment Report with a detailed wave plan. I download the report to review the proposed modernization plan. The report includes an executive summary, wave plan, dependencies between databases and code repositories, and complexity analysis.

View SQL Modernization Assessment Report

Wave transformation at scale
The wave plan generated by AWS Transform consists of four steps for each wave. First, it converts the SQL Server schema to PostgreSQL. Second, it migrates the data. Third, it transforms the dependent .NET application code to make it PostgreSQL compatible. Finally, it deploys the application for testing.

Before converting the SQL Server schema, I can either create a new PostgreSQL database or choose an existing one as the target database.

Choose or create target database

After I choose the source and target databases, AWS Transform generates conversion reports for my review. AWS Transform converts the SQL Server schema to PostgreSQL-compatible structures, including tables, indexes, constraints, and stored procedures.

Download Schema conversion reports

For any schema that AWS Transform can’t automatically convert, I can manually address them in the AWS Database Migration Service (AWS DMS) console. Alternatively, I can fix them in my preferred SQL editor and update the target database instance.

After completing schema conversion, I have the option to proceed with data migration, which is an optional step. AWS Transform uses AWS DMS to migrate data from my SQL Server instance to the PostgreSQL database instance. I can choose to perform data migration later, after completing all transformations, or work with test data by loading it into my target database.

Choose if you would like to migrate data

The next step is code transformation. I specify a target branch for AWS Transform to upload the transformed code artifacts. AWS Transform updates the codebase to make the application compatible with the converted PostgreSQL database.

Specify target branch destination for transformed codebase

With this release, AWS Transform for full-stack Windows modernization supports only codebases in .NET 6 or later. For codebases in .NET Framework 3.1+, I first use AWS Transform for .NET to port them to cross-platform .NET. I’ll expand on this in a following section.

After the conversion is completed, I can view the source and target branches along with their code transformation status. I can also download and review the transformation report.

Download transformation report

Modernizing .NET Framework applications with UI layer
One major feature we’re releasing today is the modernization of UI frameworks from ASP.NET Web Forms to Blazor. This is added to existing support for modernizing model-view-controller (MVC) Razor views to ASP.NET Core Razor views.

As mentioned previously, if I have a .NET application in legacy .NET Framework, then I continue using AWS Transform for .NET to port it to cross-platform .NET. For legacy applications with UIs built on ASP.NET Web Forms, AWS Transform now modernizes the UI layer to Blazor along with porting the backend code.

AWS Transform for .NET converts ASP.NET Web Forms projects to Blazor on ASP.NET Core, facilitating the migration of ASP.NET websites to Linux. The UI modernization feature is enabled by default in AWS Transform for .NET on both the AWS Transform web console and Visual Studio extension.

During the modernization process, AWS Transform handles the conversion of ASPX pages, ASCX custom controls, and code-behind files, implementing them as server-side Blazor components rather than web assembly. The following project and file changes are made during the transformation:

From To Description
*.aspx, *.ascx *.razor .aspx pages and .ascx custom controls become .razor files
Web.config appsettings.json Web.config settings become appsettings.json settings
Global.asax Program.cs Global .asax code becomes Program.cs code
*.master *layout.razor Master files become layout.razor files

Image showcasing how the specific project files are transformed

Other new features in AWS Transform for .NET
Along with UI porting, AWS Transform for .NET has added support for more transformation capabilities and enhanced developer experience. These new features include the following:

  • Port to .NET 10 and .NET Standard – AWS Transform now supports porting to .NET 10, the latest Long-Term Support (LTS) release, which was released on November 11, 2025. It also supports porting class libraries to .NET Standard, a formal specification for a set of APIs that are common across all .NET implementations. Furthermore, AWS Transform is now available with AWS Toolkit for Visual Studio 2026.
  • Editable transformation report – After the assessment is complete, you can now view and customize the transformation plan based on your specific requirements and preferences. For example, you can update package replacement details.
  • Real-time transformation updates with estimated remaining time – Depending on the size and complexity of the codebase, AWS Transform can take some time to complete the porting. You can now track transformation updates in real-time along with the estimated remaining time.
  • Next steps markdown – After the transformation is complete, AWS Transform now generates a next steps markdown file with the remaining tasks to complete the porting. You can use this as a revised plan to repeat the transformation with AWS Transform or use AI code-companions to complete the porting.

Things to know
Some more things to know are:

  • AWS Regions – AWS Transform for full-stack Windows modernization is generally available today in the US East (N. Virginia) Region. For Regional availability and future roadmap, visit the AWS Capabilities by Region.
  • Pricing – Currently, there is no added charge for Windows modernization features of AWS Transform. Any resources you create or continue to use in your AWS account using the output of AWS Transform are billed according to their standard pricing. For limits and quotas, refer to the AWS Transform User Guide.
  • SQL Server versions supported – AWS Transform supports the transformation of SQL Server versions from 2008 R2 through 2022, including all editions (Express, Standard, and Enterprise). SQL Server must be hosted on Amazon RDS or Amazon EC2 in the same Region as AWS Transform.
  • Entity Framework versions supported – AWS Transform supports the modernization of Entity Framework versions 6.3 through 6.5 and Entity Framework Core 1.0 through 8.0.
  • Getting started – To get started, visit AWS Transform for full-stack Windows modernization User Guide.

– Prasad

Introducing AWS Transform custom: Crush tech debt with AI-powered code modernization

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-aws-transform-custom-crush-tech-debt-with-ai-powered-code-modernization/

Technical debt is one of the most persistent challenges facing enterprise development teams today. Studies show that organizations spend 20% of their IT budget on technical debt instead of advancing new capabilities. Whether it’s upgrading legacy frameworks, migrating to newer runtime versions, or refactoring outdated code patterns, these essential but repetitive tasks consume valuable developer time that could be spent on innovation.

Today, we’re excited to announce AWS Transform custom, a new agent that fundamentally changes how organizations approach modernization at scale. This intelligent agent combines pre-built transformations for Java, Node.js, and Python upgrades with the ability to define custom transformations. By learning specific transformation patterns and automating them across entire codebases, customers using AWS Transform custom have achieved up to 80% reduction in execution time in many cases, freeing developers to focus on innovation.

You can define transformations using your documentation, natural language descriptions, and code samples. The service then applies these specific patterns consistently across hundreds or thousands of repositories, improving its effectiveness through both explicit feedback and implicit signals like developers’ manual fixes within your transformation projects.

AWS Transform custom offers both CLI and web interfaces to suit different modernization needs. You can use the CLI to define transformations through natural language interactions and execute them on local codebases, either interactively or autonomously. You can also integrate it into code modernization pipelines or workflows, making it ideal for machine-driven automation. Meanwhile, the web interface provides comprehensive campaign management capabilities, helping teams track and coordinate transformation progress across multiple repositories at scale.

Language and framework modernization
AWS Transform supports runtime upgrades without the need to provide additional information, understanding not only the syntax changes required but also the subtle behavioral differences and optimization opportunities that come with newer versions. The same intelligent approach applies to Node.js, Python and Java runtime upgrades, and even extends to infrastructure-level transitions, such as migrating workloads from x86 processors to AWS Graviton.

It also navigates framework modernization with sophistication. When organizations need to update their Spring Boot applications to take advantage of newer features and security patches, AWS Transform custom doesn’t merely update version numbers but understands the cascading effects of dependency changes, configuration updates, and API modifications.

For teams facing more dramatic shifts, such as migrating from Angular to React, AWS Transform custom can learn the patterns of component translation, state management conversion, and routing logic transformation that make such migrations successful.

Infrastructure and enterprise-scale transformations
The challenge of keeping up with evolving APIs and SDKs becomes particularly acute in cloud-based environments where services are continuously improving. AWS Transform custom supports AWS SDK updates across a broad spectrum of programming languages that enterprises use including Java, Python, and JavaScript. The service understands not only the mechanical aspects of API changes, but also recognizes best practices and optimization opportunities available in newer SDK versions.

Infrastructure as Code transformations represent another critical capability, especially as organizations evaluate different tooling strategies. Whether you’re converting AWS Cloud Development Kit (AWS CDK) templates to Terraform for standardization purposes, or updating AWS CloudFormation configurations to access new service features, AWS Transform custom understands the declarative nature of these tools and can maintain the intent and structure of your infrastructure definitions.

Beyond these common scenarios, AWS Transform custom excels at addressing the unique, organization-specific code patterns that accumulate over years of development. Every enterprise has its own architectural conventions, utility libraries, and coding standards that need to evolve over time. It can learn these custom patterns and help refactor them systematically so that institutional knowledge and best practices are applied consistently across the entire application portfolio.

AWS Transform custom is designed with enterprise development workflows in mind, enabling center of excellence teams and system integrators to define and execute organization-wide transformations while application developers focus on reviewing and integrating the transformed code. DevOps engineers can then configure integrations with existing continuous integration and continuous delivery (CI/CD) pipelines and source control systems. It also includes pre-built transformations for Java, Node.js and Python runtime updates which can be particularly useful for AWS Lambda functions, along with transformations for AWS SDK modernization to help teams get started immediately.

Getting started
AWS Transform makes complex code transformations manageable through both pre-built and custom transformation capabilities. Let’s start by exploring how to use an existing transformation to address a common modernization challenge: upgrading AWS Lambda functions due to end-of-life (EOL) runtime support.

For this example, I’ll demonstrate migrating a Python 3.8 Lambda function to Python 3.13, as Python 3.8 reached EOL and is no longer receiving security updates. I’ll use the CLI for this demo, but I encourage you to also explore the web interface’s powerful campaign management capabilities.

First, I use the command atx custom def list to explore the available transformation definitions. You can also access this functionality through a conversational interface by typing only atx instead of issuing the command directly, if you prefer.

This command displays all available transformations, including both AWS-managed defaults and any existing custom transformations created by users in my organization. AWS-managed transformations are identified by the AWS/ prefix, indicating they’re maintained and updated by AWS. In the results, I can see several options such as AWS/java-version-upgrade for Java runtime modernization, AWS/python-boto2-to-boto3-migration for updating Python AWS SDK usage, AWS/nodejs-version-upgrade for Node.js runtime updates.

For my Python 3.8 to 3.13 migration, I’ll use the AWS/python-version-upgrade transformation.

You run a migration by using the atx custom def exec command.  Please consult the documentation for more details about the command and all its options. Here, I run it against my project repository specifying the transformation name. I also add pytest to run unit tests for validation. More importantly, I use the additionalPlanContext section in the  --configuration input to specify which Python version I want to upgrade to. For reference, here’s the command I have for my demo (I’ve used multiple lines and indented it here for clarity):

atx custom def exec 
-p /mnt/c/Users/vasudeve/Documents/Work/Projects/ATX/lambda/todoapilambda 
-n AWS/python-version-upgrade
-C "pytest" 
--configuration 
    "additionalPlanContext= The target Python version to upgrade to is Python 3.13" 
-x -t

AWS Transform then starts the migration process. It analyzes my Lambda function code, identifies Python 3.8-specific patterns, and automatically applies the necessary changes for Python 3.13 compatibility. This includes updating syntax for deprecated features, modifying import statements, and adjusting any version-specific behaviors.

After execution, it provides a comprehensive summary including a report on dependencies updated in requirements.txt with Python 3.13-compatible package versions, instances of deprecated syntax replaced with current equivalents, updated runtime configuration notes for AWS Lambda deployment, suggested test cases to validate the migration, and more. It also provides a body of evidence that serve as proof of success.

The migrated code lives in a local branch so you can review and merge when satisfied. Alternatively, you can keep providing feedback and reiterating until yo’re happy that the migration is fully complete and meets your expectations.

This automated process changes what would typically require hours of manual work into a streamlined, consistent upgrade that maintains code quality while maintaining compatibility with the newer Python runtime.

Creating a new custom transformation
While AWS-managed transformations handle common scenarios effectively, you can also create custom transformations tailored to your organization’s specific needs. Let’s explore how to create a custom transformation to see how AWS Transform learns from your specific requirements.

I type atx to initialize the atx cli and start the process.

The first thing it asks me is if I want to use one of the existing transformations or create a new one. I choose to create a new one. Notice that from here on the whole conversation takes place using natural language, not commands. I typed new one but I could have typed I want to create a new one and it would’ve understood it exactly the same.

It then prompts me to provide more information about the kind of transformation I’d like to perform. For this demo, I’m going to migrate an Angular application, so I type angular 16 to 19 application migration which prompts the CLI to search for all transformations available for this type of migration. In my case, my team has already created and made available a few Angular migrations, so it shows me those. However, it warns me that none of them is an exact match to my specific request for migrating from Angular 16 to 19. It then asks if I’d like to select from one of the existing transformations listed or create a custom one.

I choose to create a custom one by continuing to use natural language and typing create a new one as a command. Again, this could be any variation of that statement provided that you indicate your intentions clearly. It follows by asking me a few questions including whether I have any useful documentation, example code or migration guides that I can provide to help customize the transformation plan.

For this demo, I’m only going to rely on AWS Transform to provide me with good defaults. I type I don't have these details. Follow best practices. and the CLI responds by telling me that it will create a comprehensive transformation definition for migrating Angular 16 to Angular 19.  Of course, I relied on the pre-trained data to generate results based on best practices. As usual, the recommendation is to provide as much information and relevant data as possible at this stage of the process for better results. However, you don’t need to have all the data upfront. You can keep on providing data at any time› as you iterate through the process of creating the custom transformation definition.

The transformation definition is generated as a markup file containing a summary and a comprehensive sequence of implementation steps grouped logically into phases such as premigration preparation, processing and partitioning, static dependency analysis, searching and applying specific transformation rules, and step-by-step migration and iterative validation.

It’s interesting to see that AWS Transform opted for the best practice of doing incremental framework updates creating steps for migrating the application first to 17 then 18 then 19 instead of trying to go directly from 16 to 19 to minimize issues.

Note that the plan includes various stages of testing and verification to confirm that the various phases can be concluded with confidence. At the very end, it also includes a final validation stage listing exit criteria that performs a comprehensive set of tests against all aspects of the application that will be used to accept the migration as successfully complete.

After the transformation definition is created, AWS Transform asks me about what I would like to do next. I can choose to review or modify the transformation definition and I can reiterate through this process as much as I need until I arrive at one that I’m satisfied with. I can also choose to already apply this transformation definition to an Angular codebase. However, first I want to make this transformation available to my team members as well as myself so we can all use it again in the future. So, I choose option 4 to publish this transformation to the registry.

This custom transformation needs a name and a description of its objective which is displayed when users browse the registry. AWS Transforms automatically extracts those from context for me and asks me if I would like to modify them before going ahead. I like the sensible default of “Angular-16-to-19-Migration”, and the objective is clearly stated, so I choose to accept the suggestions and publish it by answering with yes, looks good.

Now that the transformation definition is created and published, I can use it and run it multiple times against any code repository. Let’s apply the transformation to a code repository with a project written in Angular 16. I now choose option 1 from the follow-up prompt and the CLI asks me for the path in my file system to the application that I want to migrate and, optionally, the build command that it should use.

After I provide that information, AWS Transform proceeds to analyze the code base and formulate a thorough step-by-step transformation plan based on the definition created earlier. After it’s done, it creates a JSON file containing the detailed migration plan specifically designed for applying our transformation definition to this code base. Similar to the process of creating the transformation definition, you can review and iterate through this plan as much as you need, providing it with feedback and adjusting it to any specific requirements you might have.

When I’m ready to accept the plan, I can use natural language to tell AWS Transform that we can start the migration process. I type looks good, proceed and watch the progress in my shell as it starts executing the plan and making the changes to my code base one step at a time.

The time it takes will vary depending on the complexity of the application. In my case, it took a few minutes to complete. After it has finished, it provides me with a transformation summary and the status of each one of the exit criteria that were included in the final verification phase of the plan alongside all the evidence to support the reported status. For example, the Application Build – Production criteria was listed as passed and some of the evidence provided included the incremental Git commits, the time that it took to complete the production build, the bundle size, the build output message, and the details about all the output files created.

Conclusion
AWS Transform represents a fundamental shift in how organizations approach code modernization and technical debt. The service helps to transform what was at one time a fragmented, team-by-team effort into a unified, intelligent capability that eliminates knowledge silos, keeping your best practices and institutional knowledge available as scalable assets across the entire organization. This helps to accelerate modernization initiatives while freeing developers to spend more time on innovation and driving business value instead of focusing on repetitive maintenance and modernization tasks.

Things to know

AWS Transform custom is now generally available. Visit the get started guide to start your first transformation campaign or check out the documentation to learn more about setting up custom transformation definitions.

Top announcements of AWS re:Invent 2025

Post Syndicated from AWS News Blog Team original https://aws.amazon.com/blogs/aws/top-announcements-of-aws-reinvent-2025/

Matt Garman stands on stage at re:Invent 2024We’re rounding up the most exciting and impactful announcements from AWS re:Invent 2025, which takes place November 30-December 4 in Las Vegas. This guide highlights the innovations that will help you build, scale, and transform your business in the cloud.

We’ll update this roundup throughout re:Invent with our curation of the major announcements from each keynote session and more. To see the complete list of all AWS launches, visit What’s New with AWS.

(This post was updated Nov. 30, 2025.)


Analytics

AWS Clean Rooms launches privacy-enhancing dataset generation for ML model training
Train ML models on sensitive collaborative data by generating synthetic datasets that preserve statistical patterns while protecting individual privacy through configurable noise levels and protection against re-identification.

Compute

Introducing AWS Lambda Managed Instances: Serverless simplicity with EC2 flexibility
Run Lambda functions on EC2 compute while maintaining serverless simplicity—enabling access to specialized hardware and cost optimizations through EC2 pricing models, with AWS handling all infrastructure management.

Containers

Announcing Amazon EKS Capabilities for workload orchestration and cloud resource management
Streamline Kubernetes development with fully managed platform capabilities that handle workload orchestration and cloud resource management, eliminating infrastructure maintenance while providing enterprise-grade reliability and security.

Networking & Content Delivery

Introducing Amazon Route 53 Global Resolver for secure anycast DNS resolution (preview)
Simplify hybrid DNS management with a unified service that resolves public and private domains globally through secure, anycast-based resolution while reducing operational overhead and maintaining consistent security controls.

Partner Network

AWS Partner Central now available in AWS Management Console
Access Partner Central directly through the AWS Console to streamline your journey from customer to Partner—manage solutions, opportunities, and marketplace listings in one unified interface with enterprise-grade security.

Security, Identity, & Compliance

Simplify IAM policy creation with IAM Policy Autopilot, a new open source MCP server for builders
Speed up AWS development with an open source tool that analyzes your code to generate valid IAM policies, providing AI coding assistants with up-to-date AWS service knowledge and reliable permission recommendations.

Introducing Amazon Route 53 Global Resolver for secure anycast DNS resolution (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/introducing-amazon-route-53-global-resolver-for-secure-anycast-dns-resolution-preview/

Today, we’re announcing Amazon Route 53 Global Resolver, a new Amazon Route 53 service that provides secure and reliable DNS resolution globally for queries from anywhere (preview). You can use Global Resolver to resolve DNS queries to public domains on the internet and private domains associated with Route 53 private hosted zones. Route 53 Global Resolver offers network administrators a unified solution to resolve queries from authenticated clients and sources in on-premises data centers, branch offices, and remote locations through globally distributed anycast IP addresses. This service includes built-in security controls including DNS traffic filtering, support for encrypted queries, and centralized logging to help organizations reduce operational overhead while maintaining compliance with security requirements.

Organizations with hybrid deployments face operational complexity when managing DNS resolution across distributed environments. Resolving public internet domains and private application domains often requires maintaining split DNS infrastructure, which increases cost and administrative burden especially when replicating to multiple locations. Network administrators must configure custom forwarding solutions, deploy Route 53 Resolver endpoints for private domain resolution, and implement separate security controls across different locations. Additionally, they must configure and maintain multi-Region failover strategies for Route 53 Resolver endpoints and provide consistent security policy enforcement across all Regions while testing failover scenarios.

Route 53 Global Resolver has key capabilities that address these challenges. The service resolves both public internet domains and Route 53 private hosted zones, eliminating the need for separate split-DNS forwarding. It provides DNS resolution through multiple protocols, including DNS over UDP (Do53), DNS-over-HTTPS (DoH), and DNS-over-TLS (DoT). Each deployment provides a single set of common IPv4 and IPv6 anycast IP addresses that route queries to the nearest AWS Region, reducing latency for distributed client populations.

Route 53 Global Resolver provides integrated security features equivalent to Route 53 Resolver DNS Firewall. Administrators can configure filtering rules using AWS Managed Domain Lists that provide flexible controls with lists classified by DNS threats (malware, spam, phishing) or web content (adult sites, gambling, social networking) that might not be safe for work or create custom domain lists by importing domains from a file. Advanced threat protection detects and blocks domain generation algorithm (DGA) patterns and DNS tunneling attempts. For encrypted DNS traffic, Route 53 Global Resolver supports DoH and DoT protocols to protect queries from unauthorized access during transit.

Route 53 Global Resolver only accepts traffic from known clients that need to authenticate with the Resolver. For Do53, DoT, and DoH connections, administrators can configure IP and CIDR allowlists. For DoH and DoT connections, token-based authentication provides granular access control with customizable expiration periods and revocation capabilities. Administrators can assign tokens to specific client groups or individual devices based on organizational requirements.

Route 53 Global Resolver supports DNSSEC validation to verify the authenticity and integrity of DNS responses from public nameservers. It also includes EDNS Client Subnet support, which forwards client subnet information to enable more accurate geographic-based DNS responses from content delivery networks.

Getting started with Route 53 Global Resolver
This walkthrough shows how to configure Route 53 Global Resolver for an organization with offices on the US East and West coasts that needs to resolve both public domains and private applications hosted in Route 53 private hosted zones. To configure Route 53 Global Resolver, go to the AWS Management Console, choose Global resolvers from the navigation pane, and choose Create global resolver.

In the Resolver details section, enter a Resolver name such as corporate-dns-resolver. Add an optional description like DNS resolver for corporate offices and remote clients. In the Regions section, choose the AWS Regions where you want the resolver to operate, such as US East (N. Virginia) and US West (Oregon). The anycast architecture routes DNS queries from your clients to the nearest selected Region.

After the resolver is created, the console displays the resolver details, including the anycast IPv4 and IPv6 addresses that you will use for DNS queries. You can proceed to create a DNS view by choosing Create DNS view to configure client authentication and DNS query resolution settings.

In the Create DNS view section, enter a DNS view name such as primary-view and optionally add a Description like DNS view for corporate offices. A DNS view helps you create different logical groupings for your clients and sources, and determine the DNS resolution for those groups. This helps you maintain different DNS filtering rules and private hosted zone resolution policies for different clients in your organization.

For DNSSEC validation, choose Enable to verify the authenticity of DNS responses from public DNS servers. For Firewall rules fail open behavior, choose Disable to block DNS queries when firewall rules can’t be evaluated, which provides additional security. For EDNS client subnet, keep Enable selected to forward client location information to DNS servers, which allows content delivery networks to provide more accurate geographic responses. DNS view creation might take a few minutes to become operational.

After the DNS view is created and operational, configure DNS Firewall rules to filter network traffic by choosing Create rule. In the Create DNS Firewall rules section, enter a Rule name such as block-malware-domains and optionally add a description. For Rule configuration type, you can choose Customer managed domain lists, AWS managed domain lists provided by AWS or DNS Firewall Advanced protection.

For this walkthrough, choose AWS managed domain lists. In the Domain lists dropdown, choose one or more AWS managed lists such as Threat – Malware to block known malicious domains. You can leave Query type empty to apply the rule to all DNS query types. In this example, choose A to apply this rule only to IPv4 address queries. In the Rule action section, select Block to prevent DNS resolution for domains that match the selected lists. For Response to send for Block action, keep NODATA selected to indicate that the query was successful but no response is available, then choose Create rules.

The next step is to configure access sources to specify which IP addresses or CIDR blocks are allowed to send DNS queries to the resolver. Navigate to the Access sources tab in the DNS view and then choose Create access source.

In the Access source details section, enter a Rule name such as office-networks to identify the access source. In the CIDR block field, enter the IP address range for your offices to allow queries from that network. For Protocol, select Do53 for standard DNS queries over UDP or choose DoH or DoT if you want to require encrypted DNS connections from clients. After configuring these settings, choose Create access source to allow the specified network to send DNS queries to the resolver.

Next, navigate to the Access tokens tab in the DNS view to create token-based authentication for clients and choose Create access token. In the Access token details section, enter a Token name such as remote-clients-token. For Token expiry, select an expiration period from the dropdown based on your security requirements, such as 365 days for long-term client access, or choose a shorter duration like 30 days or 90 days for tighter access control. After configuring these settings, choose Create access token to generate the token, which clients can use to authenticate DoH and DoT connections to the resolver.

After the access token is created, navigate to the Private hosted zones tab in the DNS view to associate Route 53 private hosted zones with the DNS view so that the resolver can resolve queries for your private application domains. Choose Associate private hosted zone and in the Private hosted zones section, select a private hosted zone from the list that you want the resolver to handle. After selecting the zone, choose Associate to enable the resolver to respond to DNS queries for these private domains from your configured access sources.

With the DNS view configured, firewall rules created, access sources and tokens defined, and private hosted zones associated, the Route 53 Global Resolver setup is complete and ready to handle DNS queries from your configured clients.

After creating your Route 53 Global Resolver, you need to configure your DNS clients to send queries to the resolver’s anycast IP addresses. The configuration method depends on the access control you configured in your DNS view:

  • For IP-based access sources (CIDR blocks) – Configure your source clients to point DNS traffic to the Route 53 Global Resolver anycast IP addresses provided in the resolver details. Global Resolver will only allow access from allowlisted IPs that you have specified in your access sources. You can also associate the access sources to different DNS views to provide more granular DNS resolution views for different sets of IPs.
  • For access token–based authentication – Deploy the tokens on your clients to authenticate DoH and DoT connections with Route 53 Global Resolver. You must also configure your clients to point the DNS traffic to the Route 53 Global Resolver anycast IP addresses provided in the resolver details.

For detailed configuration instructions for your specific operating system and protocol, refer to the technical documentation.

Additional things to know
We’re renaming the existing Route 53 Resolver to Route 53 VPC Resolver. This naming change clarifies the architectural distinction between the two services. VPC Resolver operates Regionally within your VPCs to provide DNS resolution for resources in your Amazon VPC environment. VPC Resolver continues to support inbound and outbound resolver endpoints for hybrid DNS architectures within specific AWS Regions.

Route 53 Global Resolver complements Route 53 VPC Resolver by providing internet-reachable, global and private DNS resolution for on-premises and remote clients without requiring VPC deployment or private connections.

Existing VPC Resolver configurations remain unchanged and continue to function as configured. The renaming affects the service name in the AWS Management Console and documentation, but API operation names remain unchanged. If your architecture requires DNS resolution for resources within your VPCs, continue using VPC Resolver.

Join the preview
Route 53 Global Resolver reduces operational overhead by providing unified DNS resolution for public and private domains through a single managed service. The global anycast architecture improves reliability and reduces latency for distributed clients. Integrated security controls and centralized logging help organizations maintain consistent security policies across all locations while meeting compliance requirements.

To learn more about Amazon Route 53 Global Resolver, visit the Amazon Route 53 documentation.

You can start using Route 53 Global Resolver through the AWS Management Console in US East (N. Virginia), US East (Ohio), US West (N. California), US West (Oregon), Europe (Frankfurt), Europe (Ireland), Europe (London), Asia Pacific (Mumbai), Asia Pacific (Singapore), Asia Pacific (Tokyo), and Asia Pacific (Sydney) Regions.

— Esra