Tag Archives: news

Streamline the path from data to insights with new Amazon SageMaker Catalog capabilities

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/streamline-the-path-from-data-to-insights-with-new-amazon-sagemaker-capabilities/

Modern organizations manage data across multiple disconnected systems—structured databases, unstructured files, and separate visualization tools—creating barriers that slow analytics workflows and limit insight generation. Separate visualization platforms often create barriers that prevent teams from extracting comprehensive business insights.

These disconnected workflows prevent your organizations from maximizing your data investments, creating delays in decision making and missed opportunities for comprehensive analysis that combines multiple data types.

Starting today, you can use three new capabilities in Amazon SageMaker to accelerate your path from raw data to actionable insights:

  • Amazon QuickSight integration – Launch Amazon QuickSight directly from Amazon SageMaker Unified Studio to build dashboards using your project data, then publish them to the Amazon SageMaker Catalog for broader discovery and sharing across your organization.
  • Amazon SageMaker adds support for Amazon S3 general purpose buckets and Amazon S3 Access Grants in SageMaker Catalog– Make data stored in Amazon S3 general purpose buckets easier for teams to find, access, and collaborate on all types of data including unstructured data, while maintaining fine-grained access control using Amazon S3 Access Grants.
  • Automatic data onboarding from your lakehouse – Automatic onboarding of existing AWS Glue Data Catalog (GDC) datasets from the lakehouse architecture into SageMaker Catalog, without manual setup.

These new SageMaker capabilities address the complete data lifecycle within a unified and governed experience. You get automatic onboarding of existing structured data from your lakehouse, seamless cataloging of unstructured data content in Amazon S3, and streamlined visualization through QuickSight—all with consistent governance and access controls.

Let’s take a closer look at each capability.

Amazon SageMaker and Amazon QuickSight Integration
With this integration, you can build dashboards in Amazon QuickSight using data from your Amazon SageMaker projects. When you launch QuickSight from Amazon SageMaker Unified Studio, Amazon SageMaker automatically creates the QuickSight dataset and organizes it in a secured folder accessible only to project members.

Furthermore, the dashboards you build stay within this folder and automatically appear as assets in your SageMaker project, where you can publish them to the SageMaker Catalog and share them with users or groups in your corporate directory. This keeps your dashboards organized, discoverable, and governed within SageMaker Unified Studio.

To use this integration, both your Amazon SageMaker Unified Studio domain and QuickSight account must be integrated with AWS IAM Identity Center using the same IAM Identity Center instance. Additionally, your QuickSight account must exist in the same AWS account where you want to enable the QuickSight blueprint. You can learn more about the prerequisites on Documentation page. 

After these prerequisites are met, you can enable the blueprint for Amazon QuickSight by navigating to the Amazon SageMaker console and choosing the Blueprints tab. Then find Amazon QuickSight and follow the instructions.

You also need to configure your SQL analytics project profile to include Amazon QuickSight in Add blueprint deployment settings.
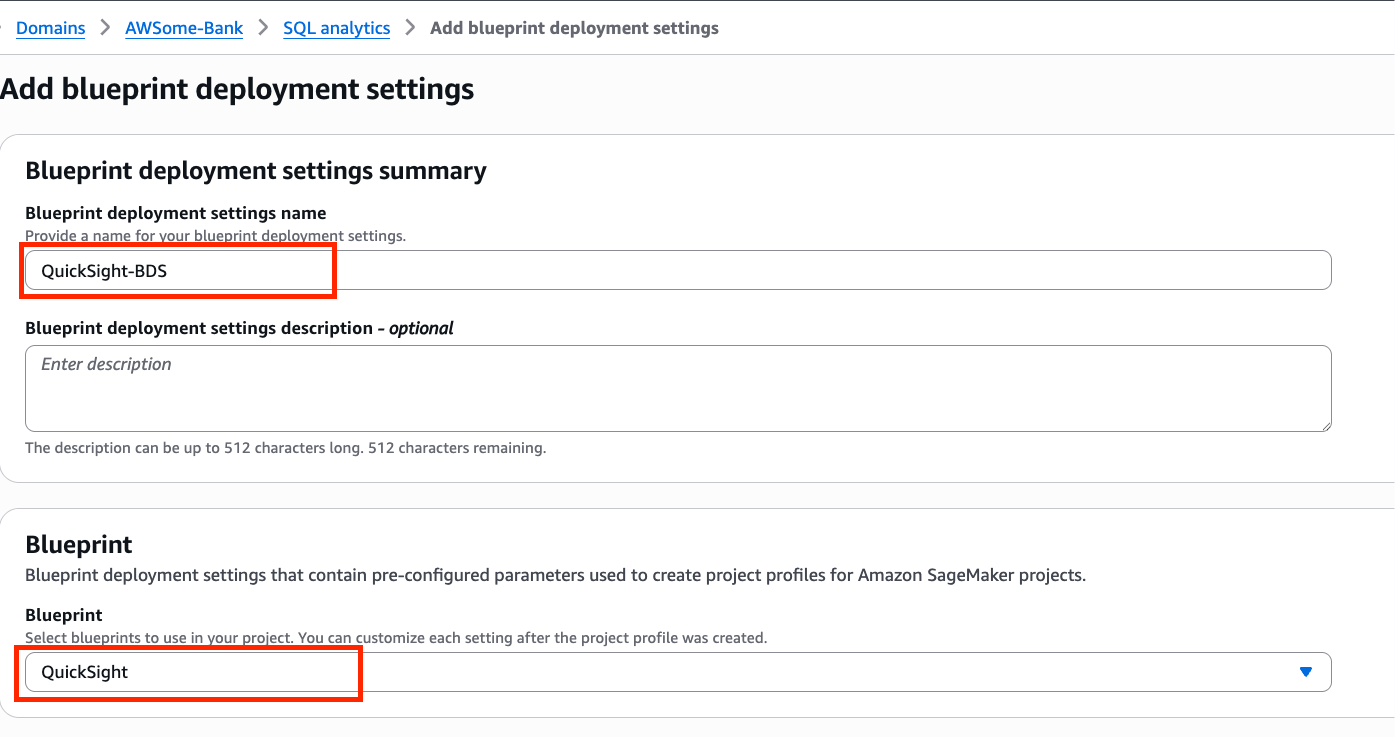
To learn more on onboarding setup, refer to the Documentation page.

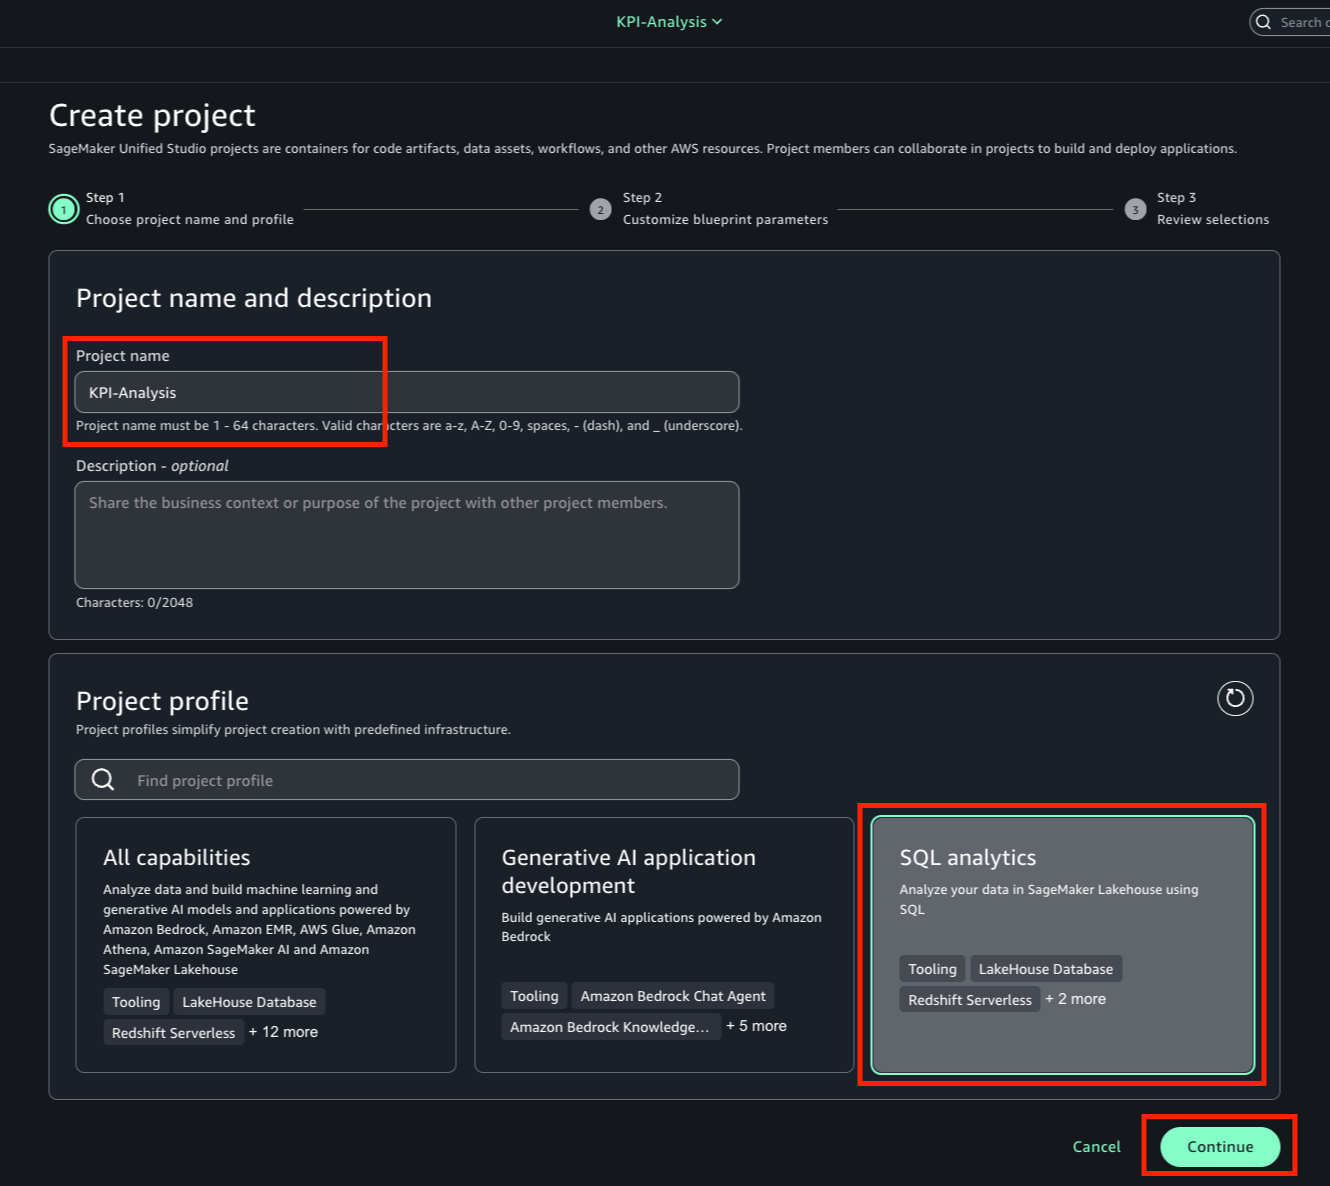
Then, when you create a new project, you need to use the SQL analytics profile.
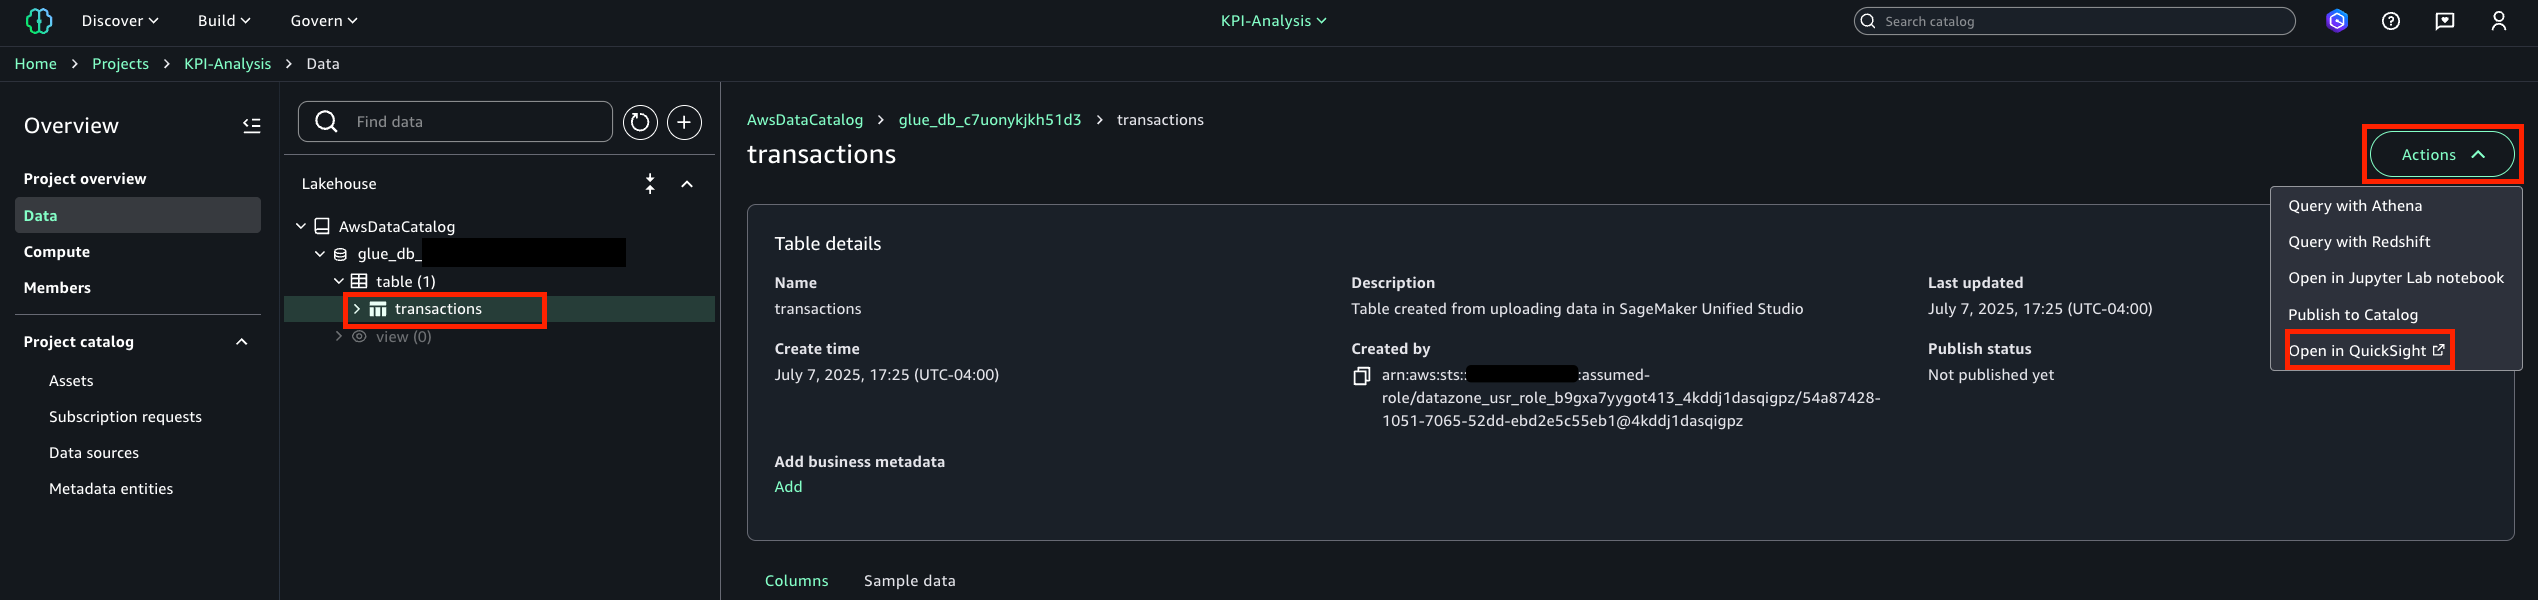
With your project created, you can start building visualizations with QuickSight. You can navigate to the Data tab, select the table or view to visualize, and choose Open in QuickSight under Actions.
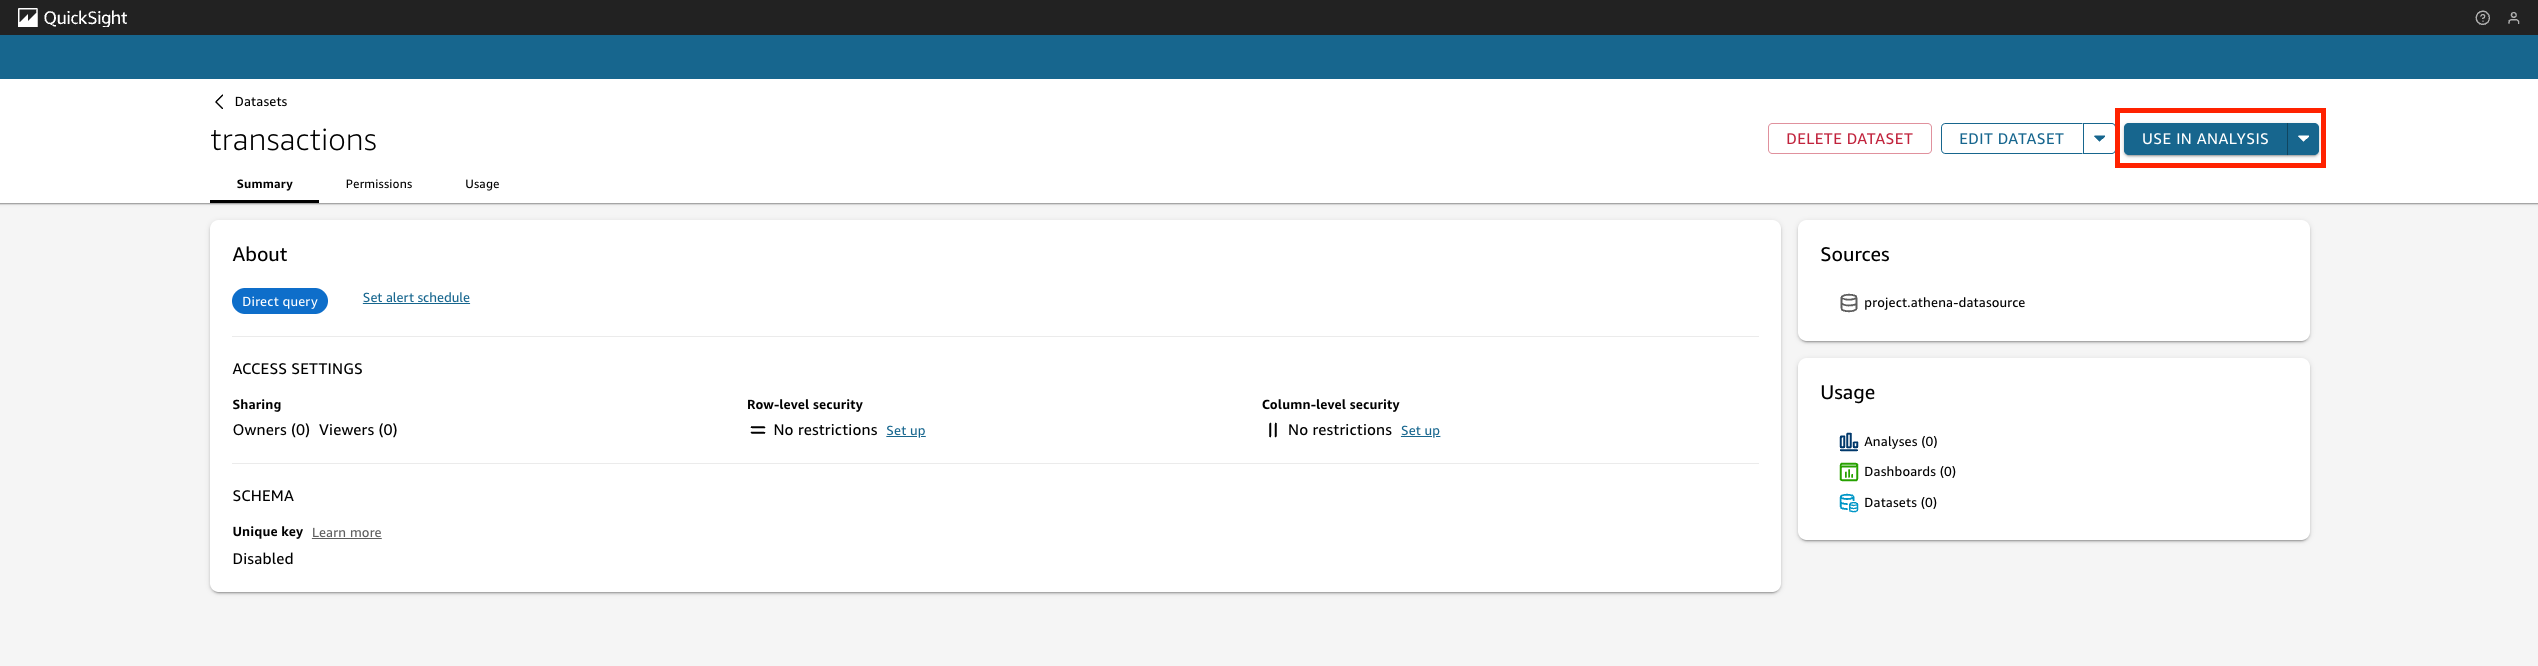
This will redirect you to the Amazon QuickSight transactions dataset page and you can choose USE IN ANALYSIS to begin exploring the data.
When you create a project with the QuickSight blueprint, SageMaker Unified Studio automatically provisions a restricted QuickSight folder per project where SageMaker scopes all new assets—analyses, datasets, and dashboards. The integration maintains real-time folder permission sync, keeping QuickSight folder access permissions aligned with project membership.

Amazon Simple Storage Service (S3) general purpose buckets integration
Starting today, SageMaker adds support for S3 general purpose buckets in SageMaker Catalog to increase discoverability and allows granular permissions through S3 Access Grants, enabling users to govern data, including sharing and managing permissions. Data consumers, such as data scientists, engineers, and business analysts, can now discover and access S3 assets through SageMaker Catalog. This expansion also enables data producers to govern security controls on any S3 data asset through a single interface.

To use this integration, you need appropriate S3 general purpose bucket permissions, and your SageMaker Unified Studio projects must have access to the S3 buckets containing your data. Learn more about prerequisites on Amazon S3 data in Amazon SageMaker Unified Studio Documentation page.

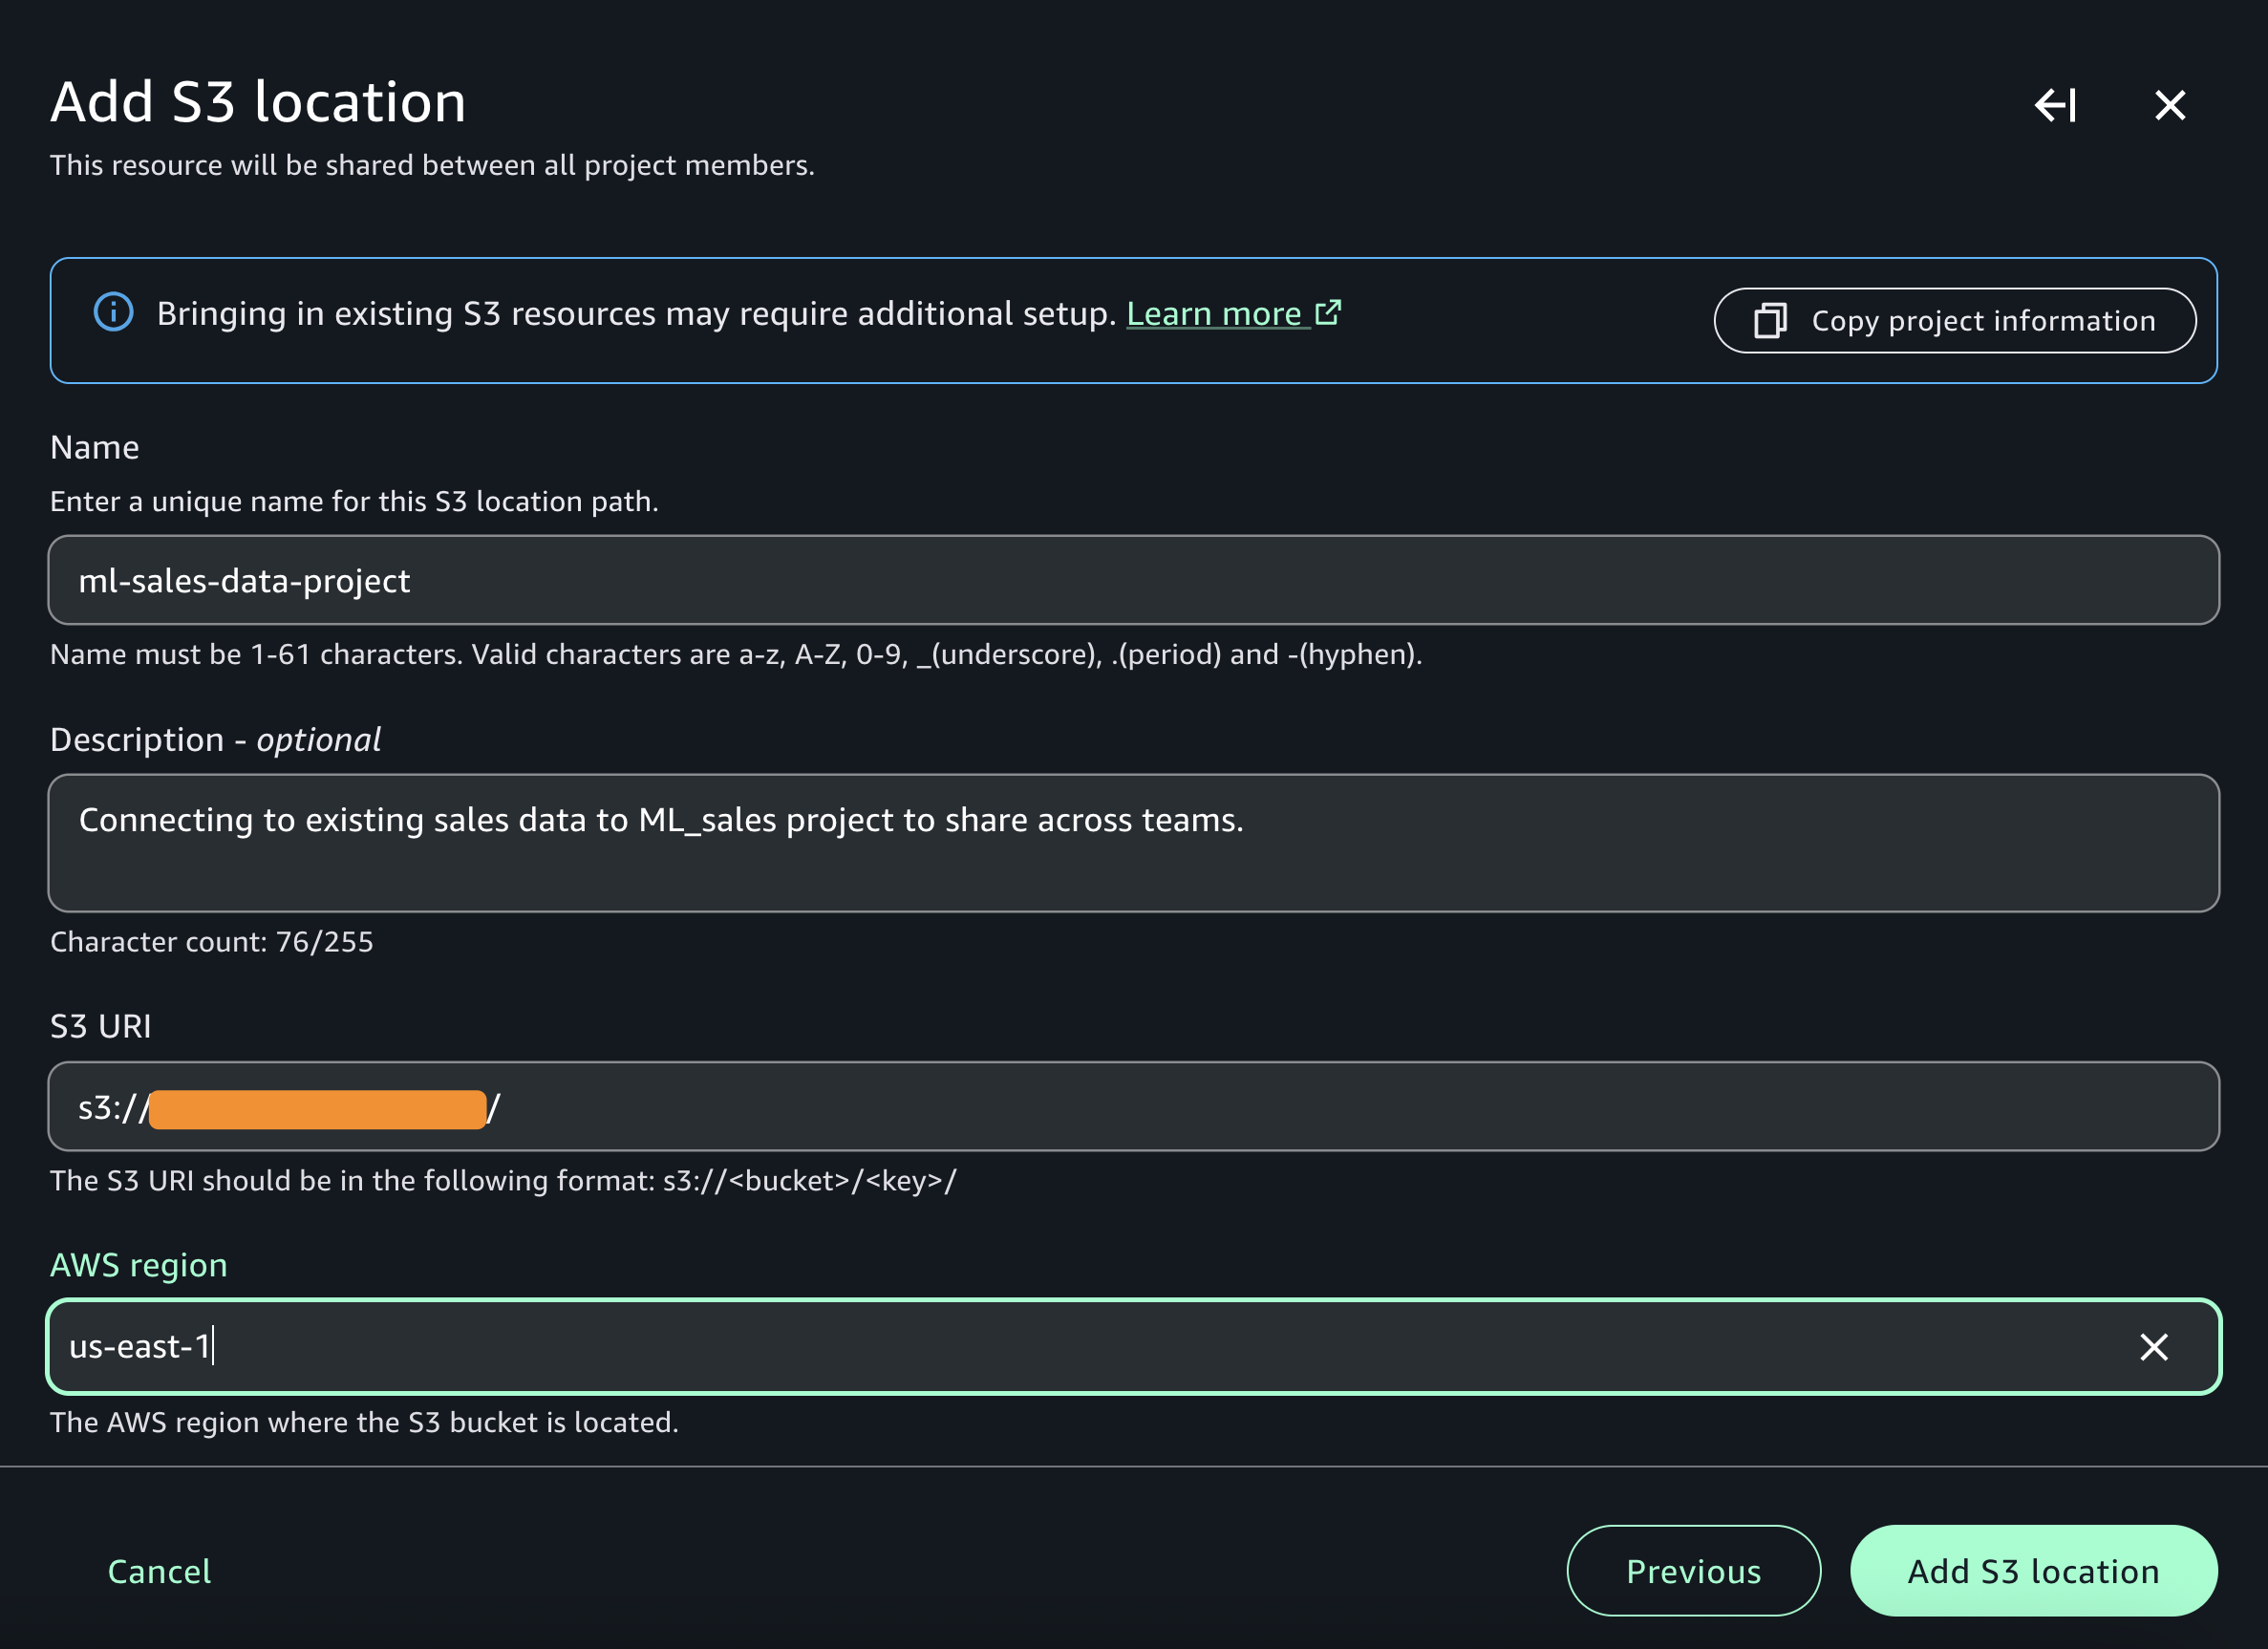
You can add a connection to an existing S3 bucket.
When it’s connected, you can browse accessible folders and create discoverable assets by choosing on the bucket or a folder and selecting Publish to Catalog.
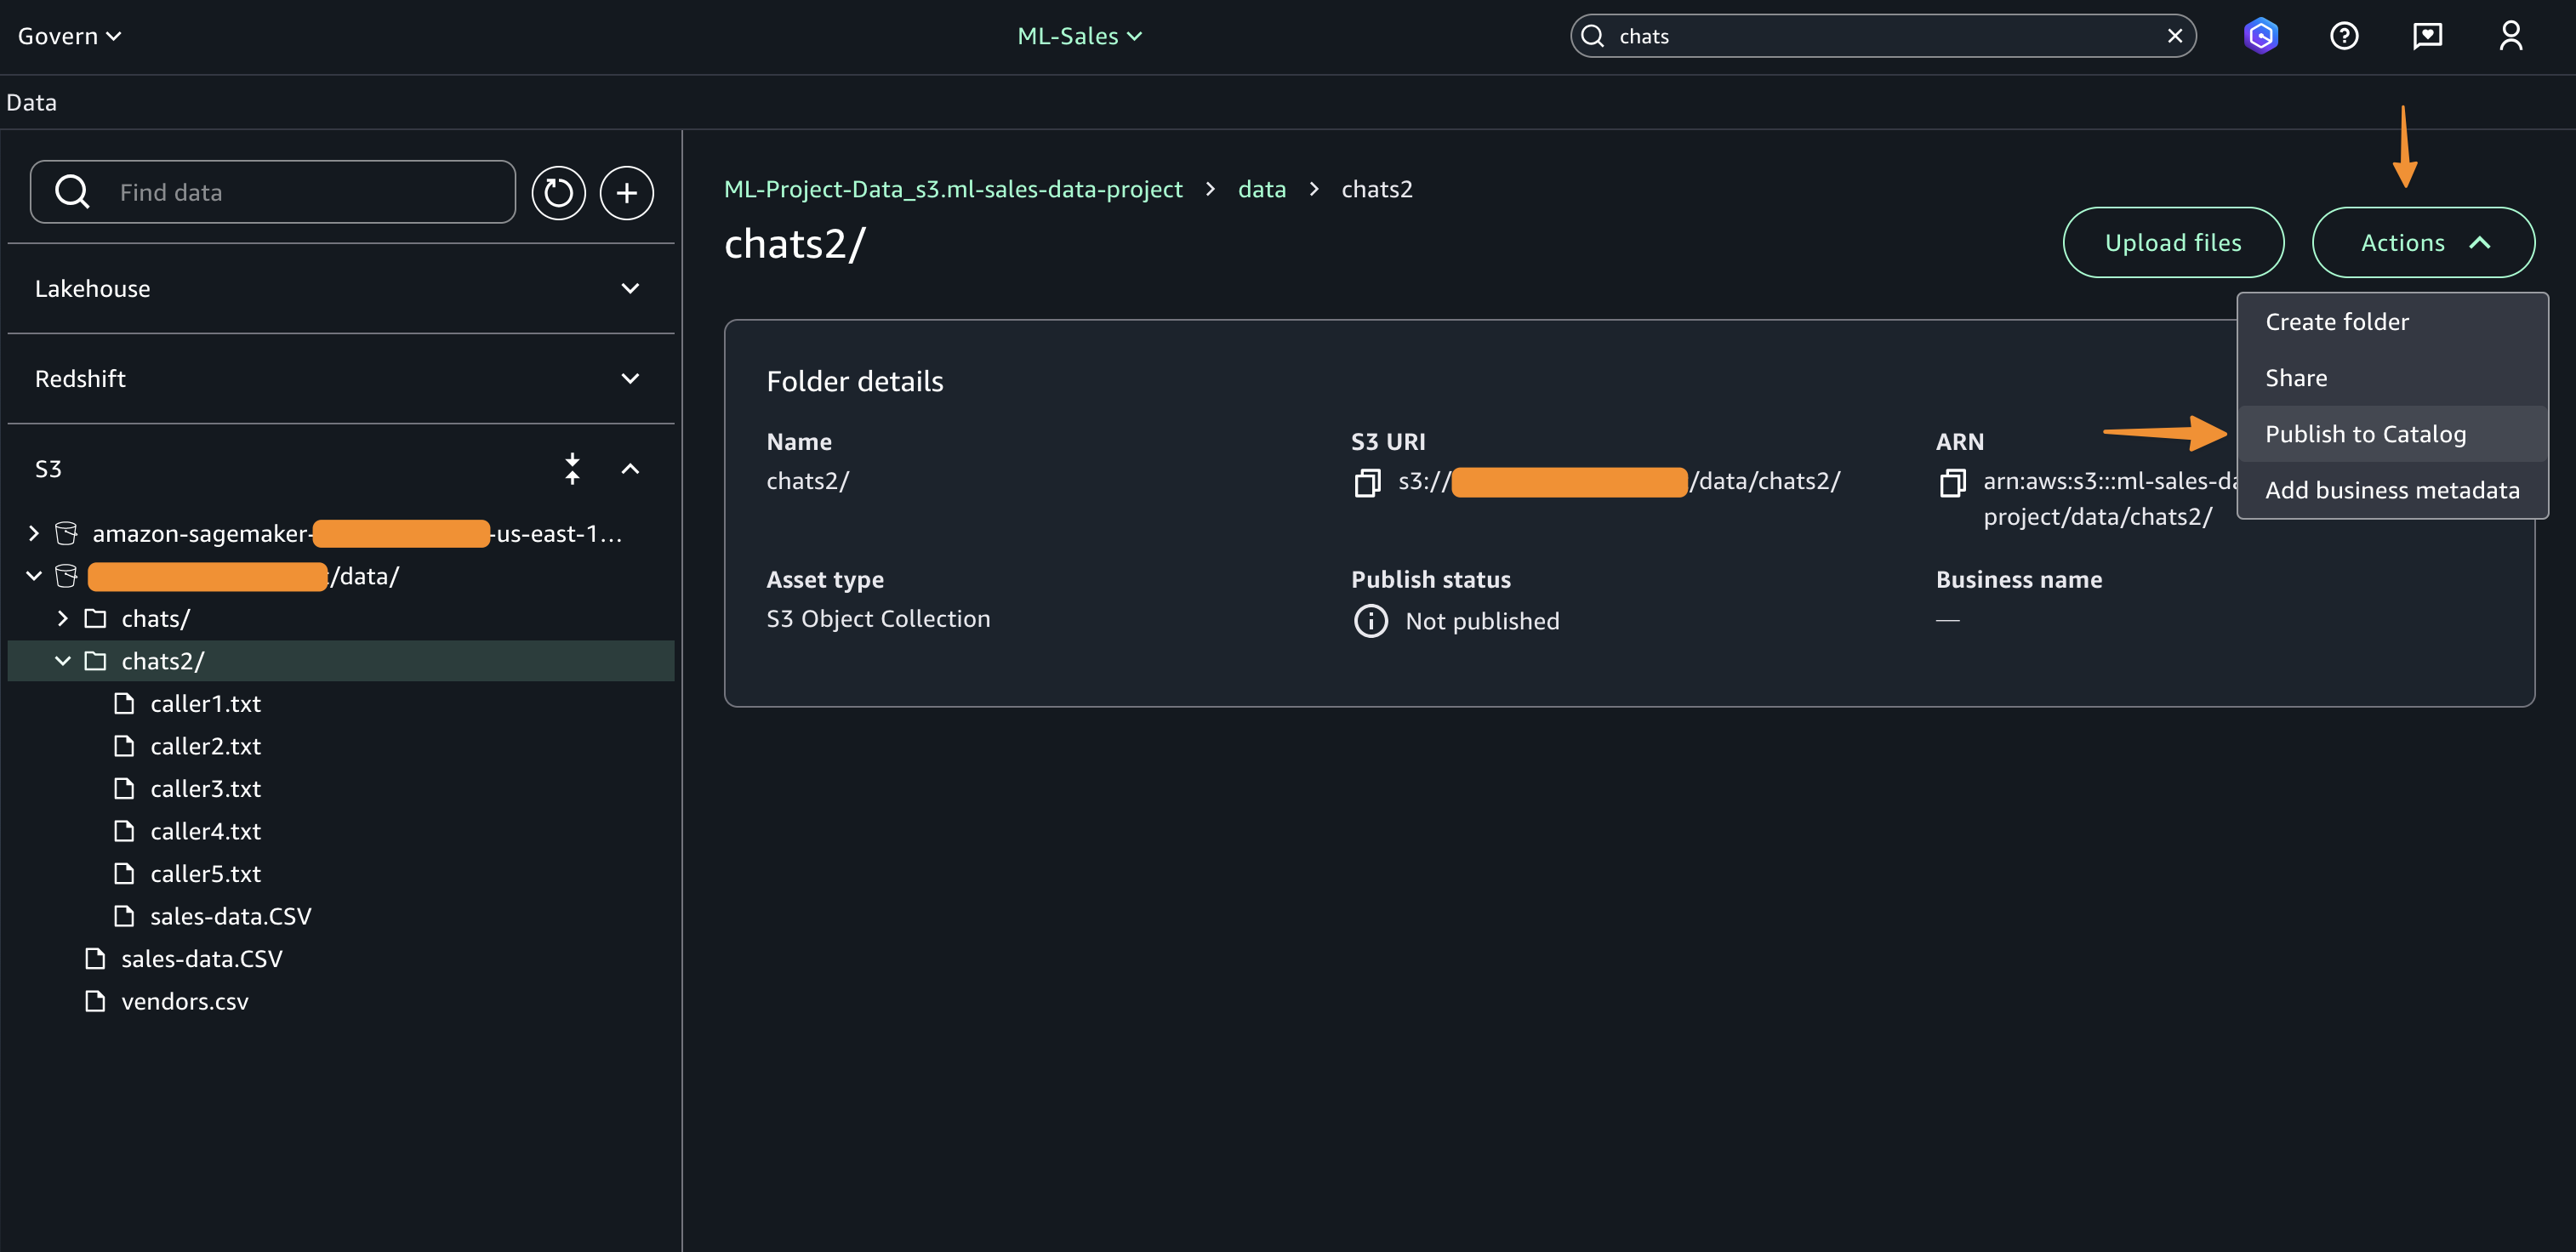
This action creates a SageMaker Catalog asset of type “S3 Object Collection” and opens an asset details page where users can augment business context to improve search and discoverability. Once published, data consumers can discover and subscribe to these cataloged assets. When data consumers subscribe to “S3 Object Collection” assets, SageMaker Catalog automatically grants access using S3 Access Grants upon approval, enabling cross-team collaboration while ensuring only the right users have the right access.
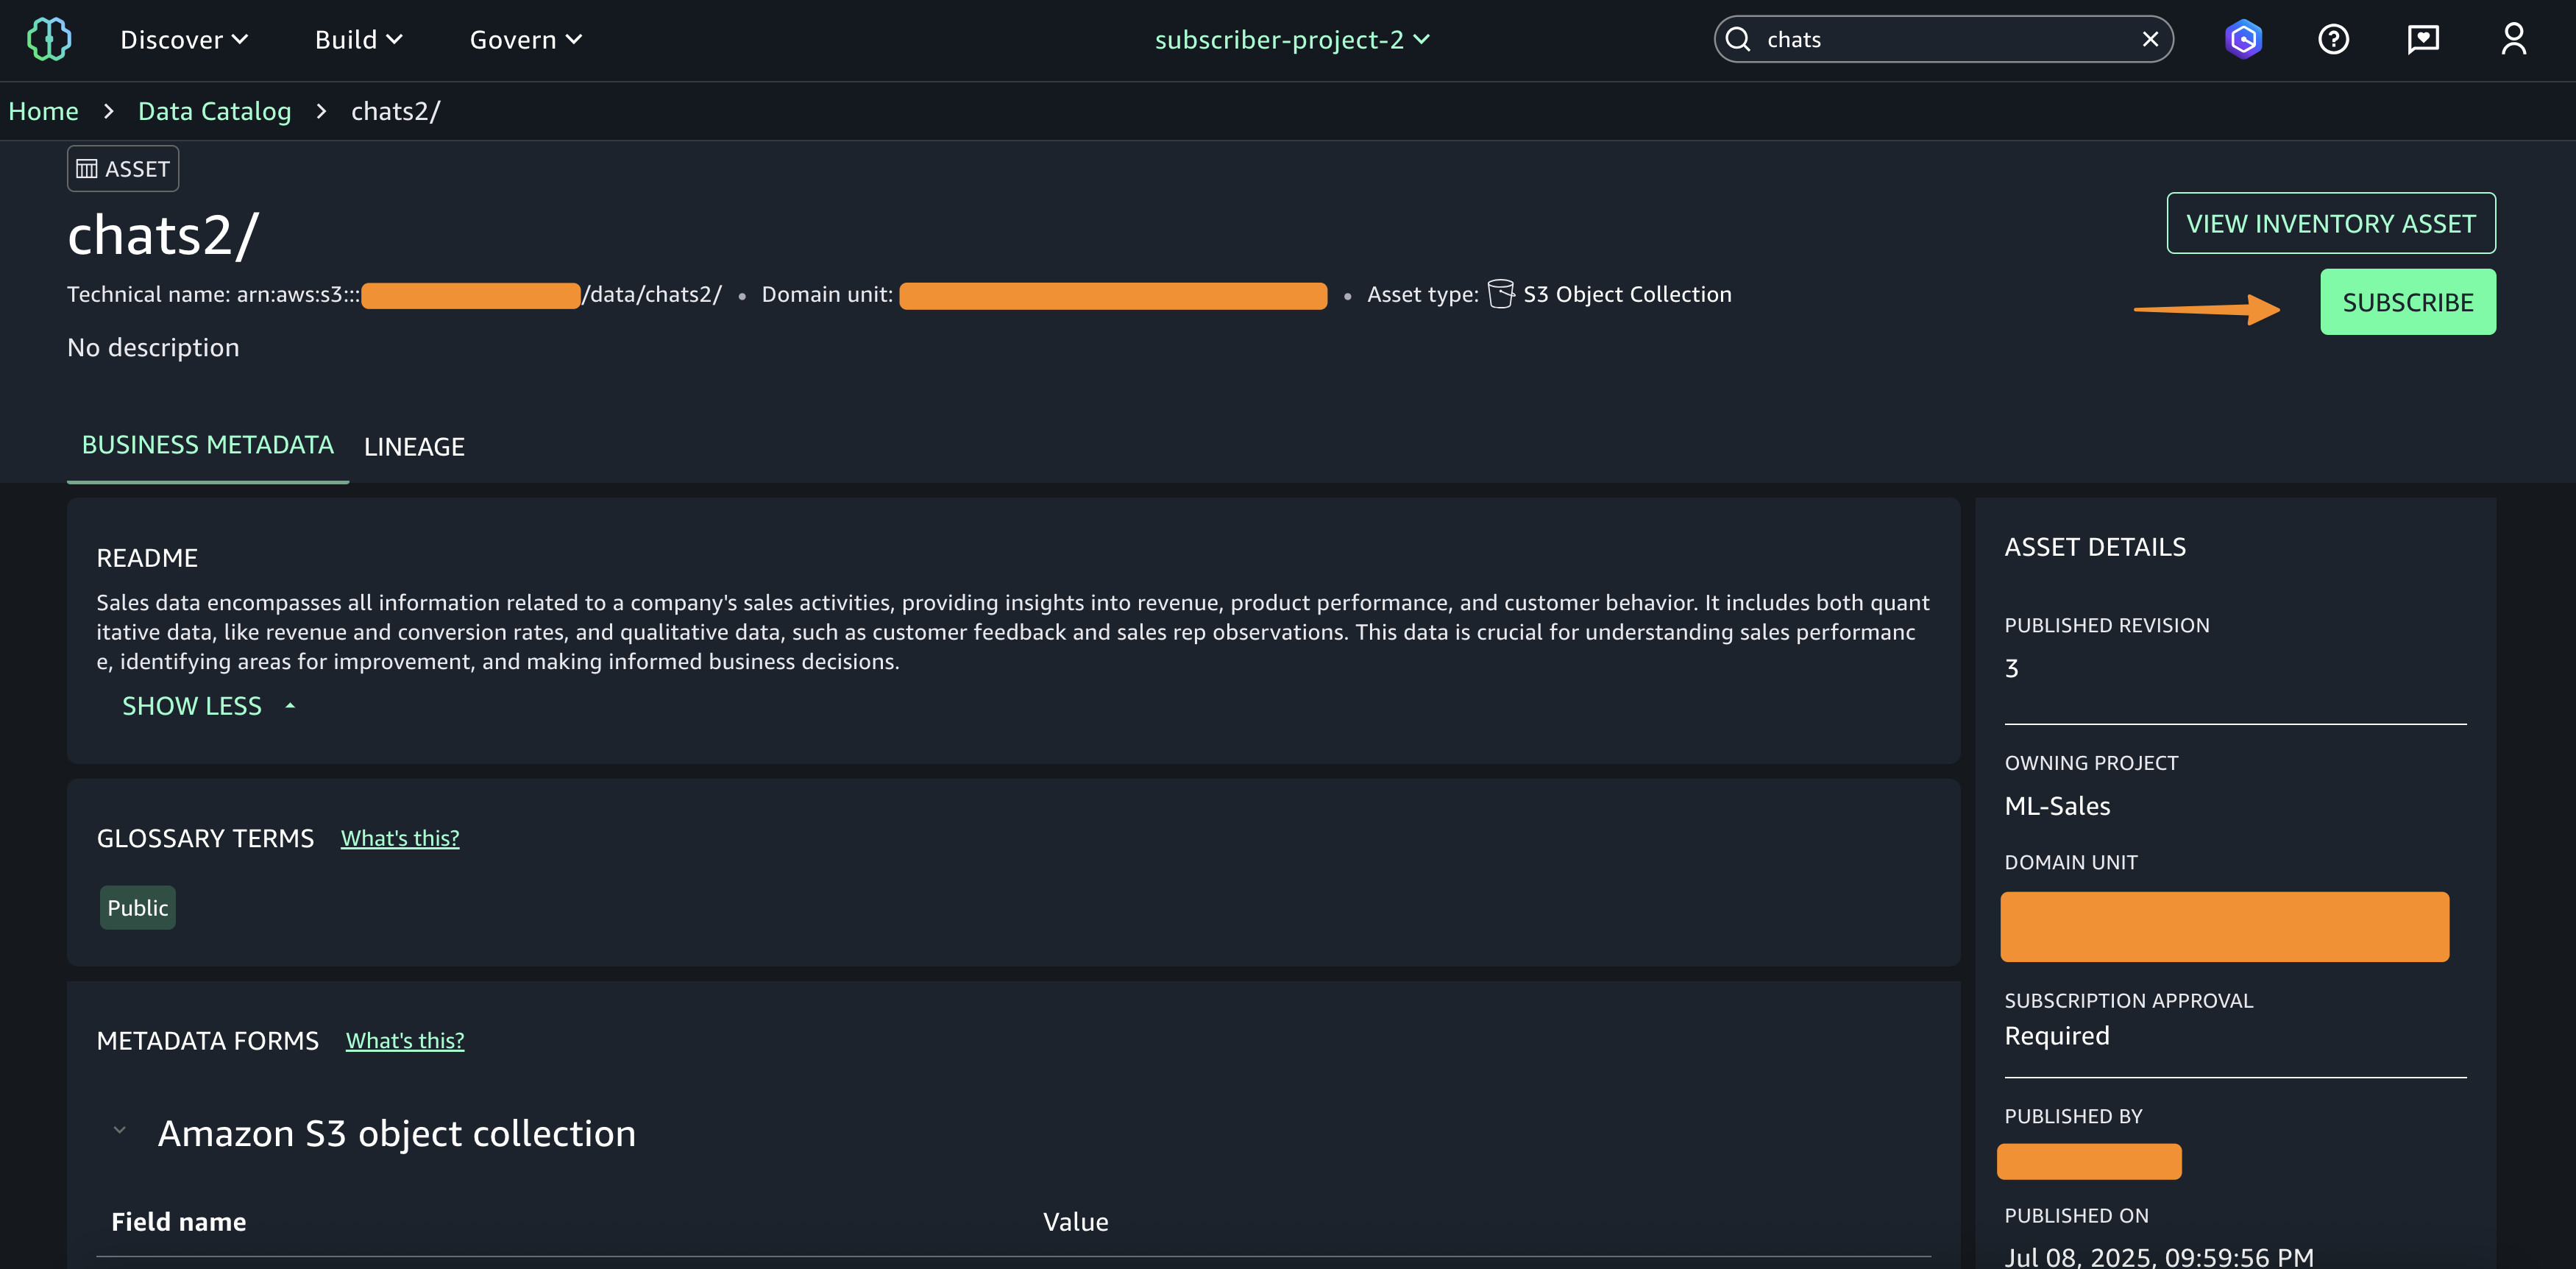
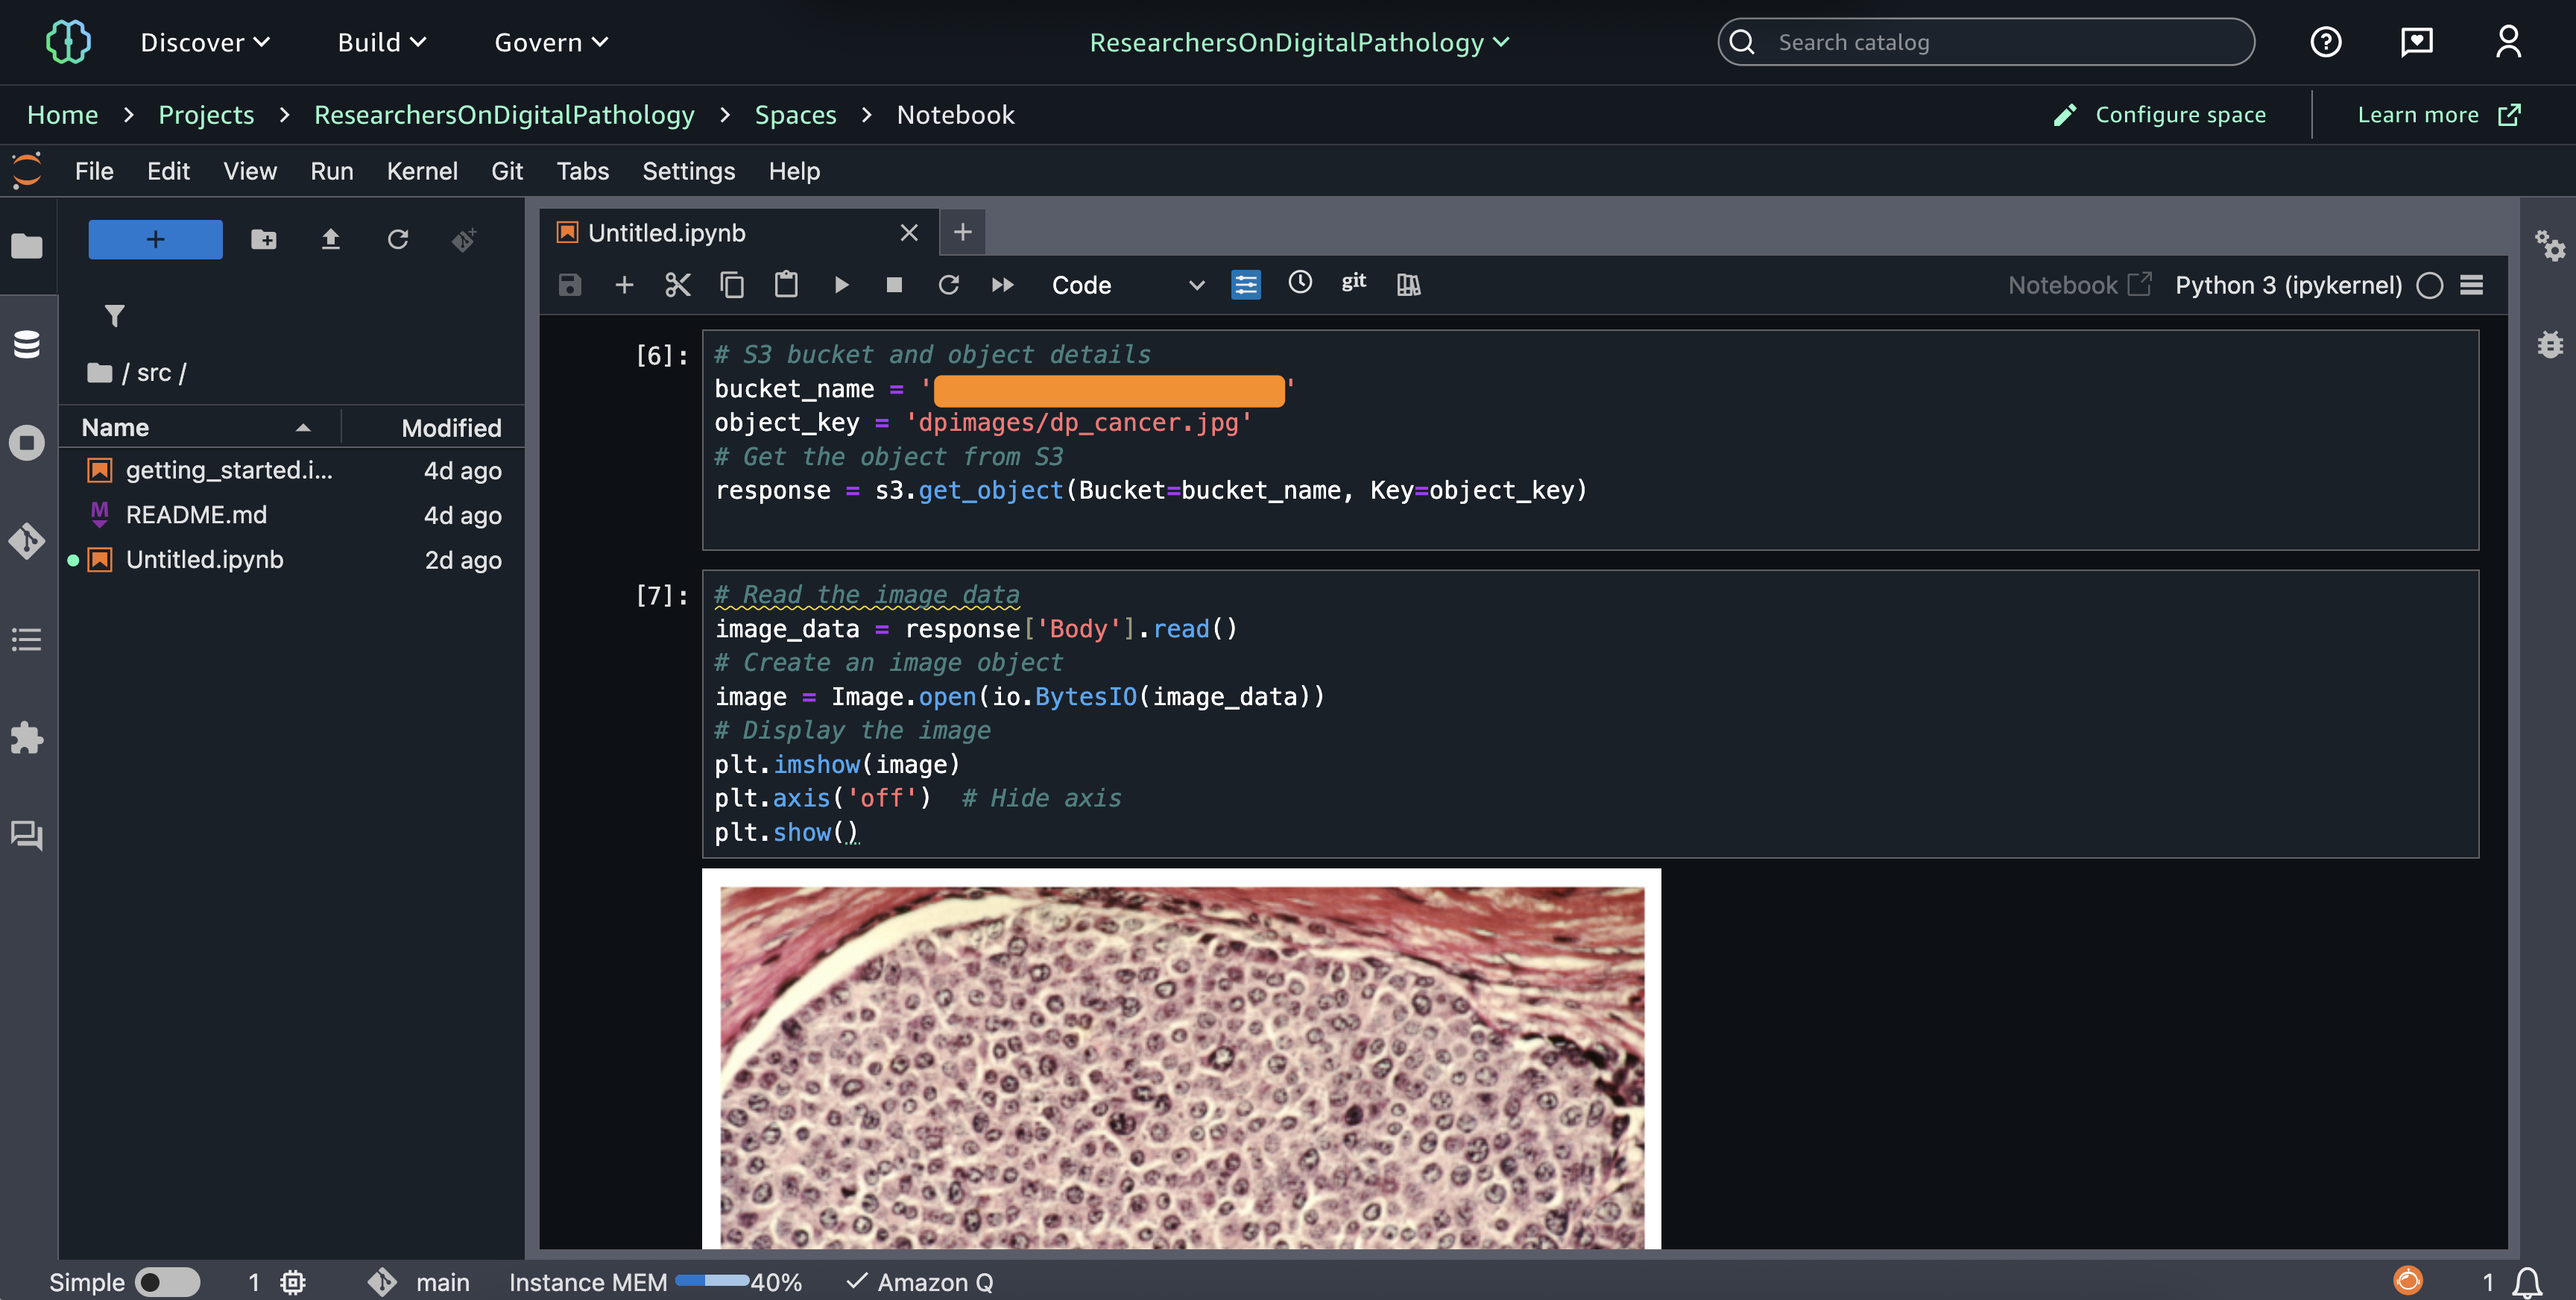
When you have access, now you can process your unstructured data in Amazon SageMaker Jupyter notebook. Following screenshot is an example to process image in medical use case.
If you have structured data, you can query your data using Amazon Athena or process using Spark in notebooks.
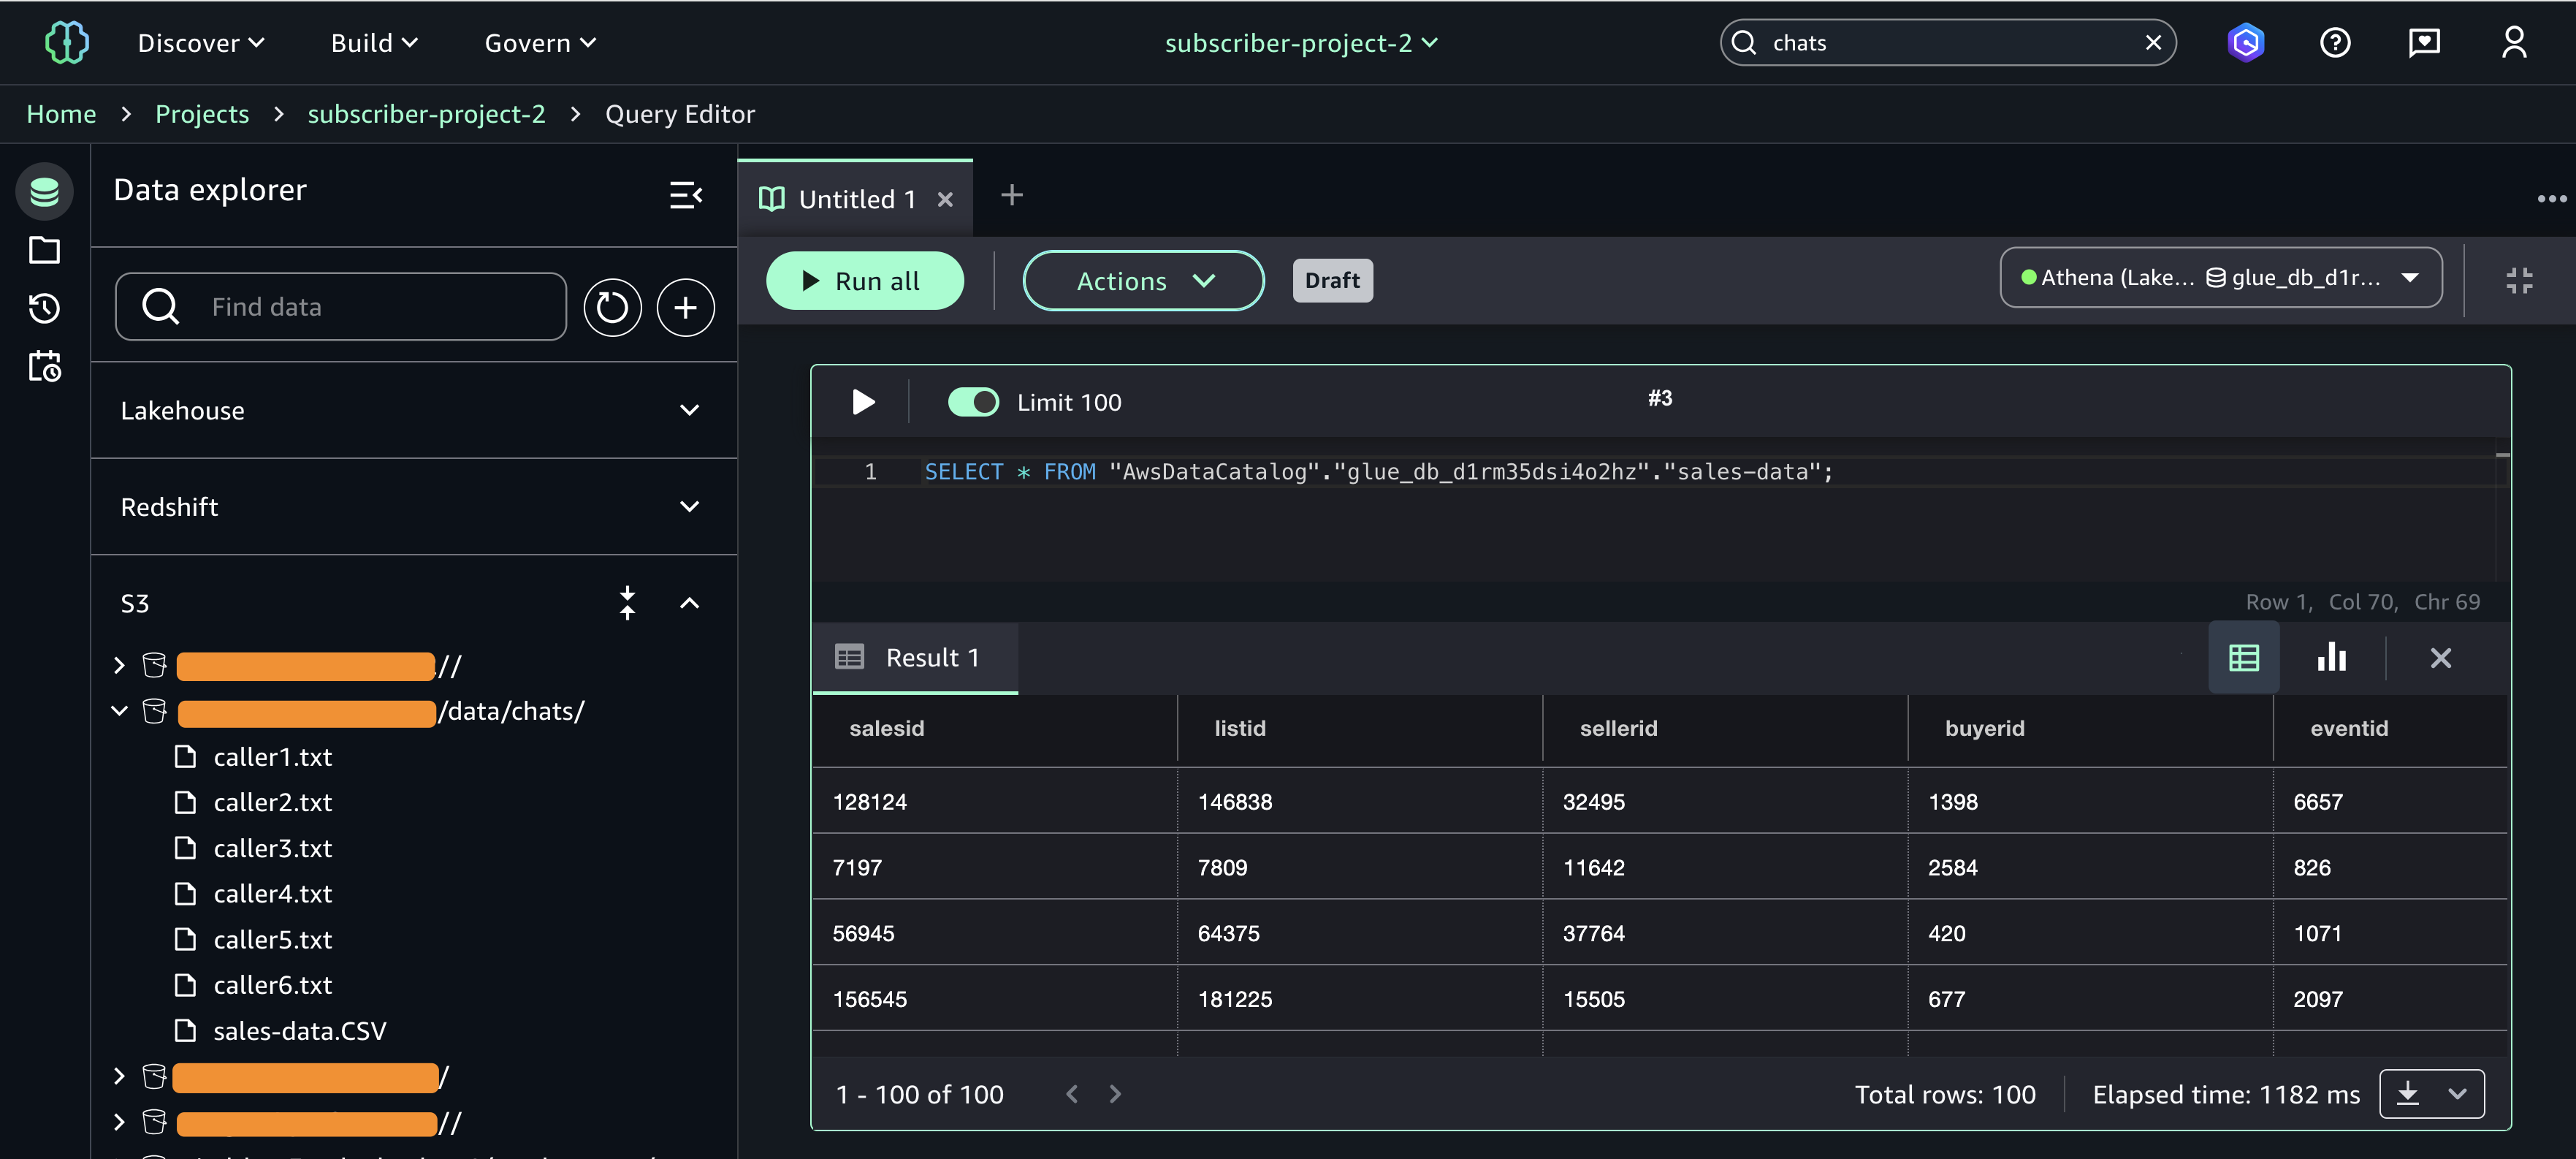
With this access granted through S3 Access Grants, you can seamlessly incorporate S3 data into my workflows—analyzing it in notebooks, combining it with structured data in the lakehouse and Amazon Redshift for comprehensive analytics. You can access unstructured data such as documents, images in JupyterLab notebooks to train ML models, or generate queryable insights.

Automatic data onboarding from your lakehouse
This integration automatically onboards all your lakehouse datasets into SageMaker Catalog. The key benefit for you is to bring AWS Glue Data Catalog (GDC) datasets into SageMaker Catalog, eliminating manual setup for cataloging, sharing, and governing them centrally.

This integration requires an existing lakehouse setup with Data Catalog containing your structured datasets.

When you set up a SageMaker domain, SageMaker Catalog automatically ingests metadata from all lakehouse databases and tables. This means you can immediately explore and use these datasets from within SageMaker Unified Studio without any configuration.
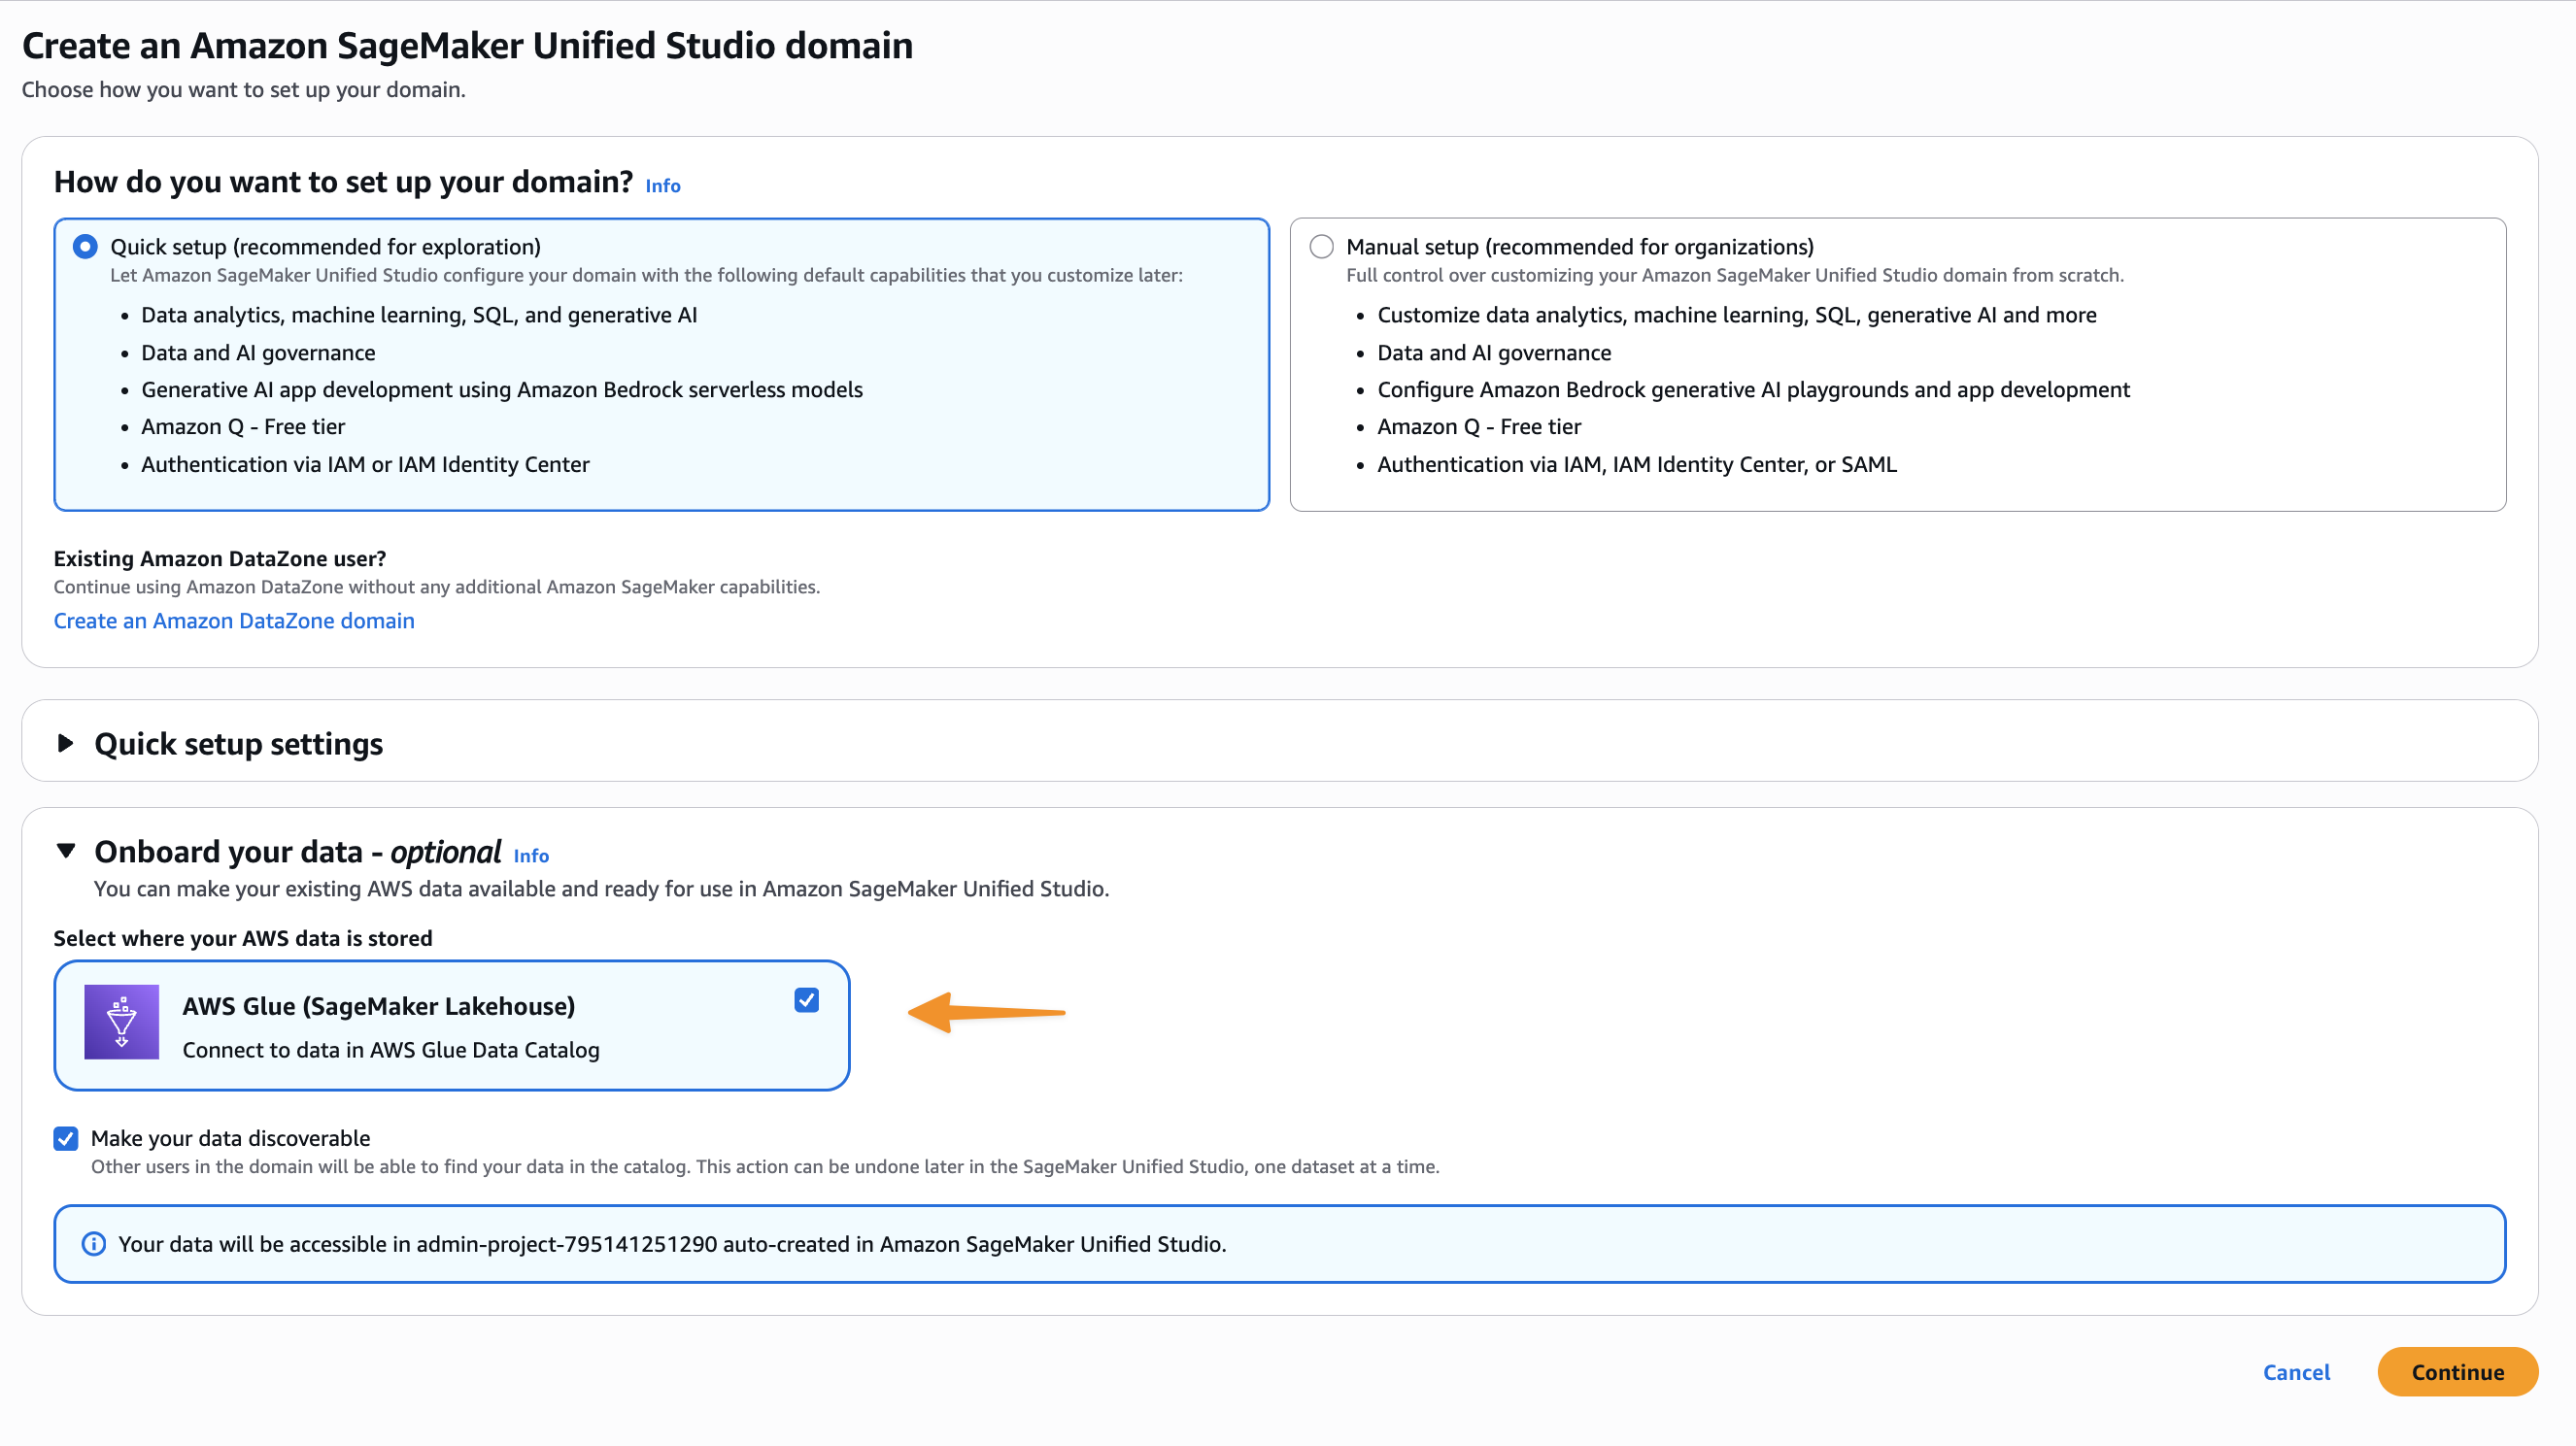
The integration helps you to start managing, governing, and consuming these assets from within SageMaker Unified Studio, applying the same governance policies and access controls you can use for other data types while unifying technical and business metadata.

Additional things to know
Here are a couple of things to note:

  • Availability – These integrations are available in all commercial AWS Regions where Amazon SageMaker is supported.
  • Pricing – Standard SageMaker Unified Studio, QuickSight, and Amazon S3 pricing applies. No additional charges for the integrations themselves.
  • Documentation – You can find complete setup guides in the SageMaker Unified Studio Documentation.

Get started with these new integrations through the Amazon SageMaker Unified Studio console.

Happy building!
— Donnie

AWS Free Tier update: New customers can get started and explore AWS with up to $200 in credits

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-free-tier-update-new-customers-can-get-started-and-explore-aws-with-up-to-200-in-credits/

When you’re new to Amazon Web Services (AWS), you can get started with AWS Free Tier to learn about AWS services, gain hands-on experience, and build applications. You can explore the portfolio of services without incurring costs, making it even easier to get started with AWS.

Today, we’re announcing some enhancements to the AWS Free Tier program, offering up to $200 in AWS credits that can be used across AWS services. You’ll receive $100 in AWS credits upon sign-up and can earn an additional $100 in credits by using services such as Amazon Elastic Compute Cloud (Amazon EC2), Amazon Relational Database Service (Amazon RDS), AWS Lambda, Amazon Bedrock, and AWS Budgets.

The enhanced AWS Free Tier program offers two options during sign-up: a free account plan and a paid account plan. The free account plan ensures you won’t incur any charges until you upgrade to a paid plan. The free account plan expires after 6 months or when you exhaust your credits, whichever comes first.

While on the free account plan, you won’t be able to use some services typically used by large enterprises. You can upgrade to a paid plan at any time to continue building on AWS. When you upgrade, you can still use any unused credits for any eligible service usage for up to 12 months from your initial sign-up date.

When you choose the paid plan, AWS will automatically apply your Free Tier credits to the use of eligible services in your AWS bills. For usage that exceeds the credits, you’re charged with the on-demand pricing.

Get up to $200 credits in action
When you sign up for either a free plan or a paid plan, you’ll receive $100 credit. You can also earn an additional $20 credits for each of these five AWS service activities you complete:

  • Amazon EC2 – You’ll learn how to launch an EC2 instance and terminate it.
  • Amazon RDS – You’ll learn the basic configuration options for launching an RDS database.
  • AWS Lambda – You’ll learn to build a straightforward web application consisting of a Lambda function with a function URL.
  • Amazon Bedrock – You’ll learn how to submit a prompt to generate a response in the Amazon Bedrock text playground.
  • AWS Budgets – You’ll learn how to set a budget that alerts you when you exceed your budgeted cost amount.

You can see the credit details in the Explore AWS widget in the AWS Management Console.

These activities are designed to expose customers to important building blocks of AWS, including cost and usage that show up in the AWS Billing Console. These charges are deducted from your Free Tier credits and help teach new AWS users about selecting the appropriate instance sizes to minimize your costs.

Choose Set up a cost budget using AWS Budgets to earn your first $20 credits. It redirects to the AWS Billing and Cost Management console.

To create your first budget, choose Use a template (simplified) and Monthly cost budget to notify you if you exceed, or are forecasted to exceed, the budget amount.

When you choose the Customize (advanced) setup option, you can customize a budget to set parameters specific to your use case, scope of AWS services or AWS Regions, the time period, the start month, and specific accounts.

After you successfully create your budget, your begin receiving alerts when your spend exceeds your budgeted amount.

You can go to the Credits page in the left navigation pane in the AWS Billing and Cost Management Console to confirm your $20 in credits. Please note, it can take up to 10 minutes for your credits to appear.

You can receive an additional $80 by completing the remaining four activities. Now you can use up to $200 in credits to learn AWS services and build your first application.

Things to know
Here are some of things to know about the enhanced AWS Free Tier program:

  • Notifications – We’ll send an email alert when 50 percent, 25 percent, or 10 percent of your AWS credits remain. We’ll also send notifications to the AWS console and your email inbox when you have 15 days, 7 days, and 2 days left in your 6-month free period. After your free period ends, we’ll send you an email with instructions on how to upgrade to a paid plan. You’ll have 90 days to reopen your account by upgrading to a paid plan.
  • AWS services – The free account can access parts of AWS services including over 30 services that offer always-free tier. The paid account can access all AWS services. For more information, visit AWS Free Tier page.
  • Legacy Free Tier – If your AWS account was created before July 15, 2025, you’ll continue to be in the legacy Free Tier program, where you can access short-term trials, 12-month trials, and always free tier services. The always-free tier is available under both the new Free Tier program and the legacy Free Tier program.

Now available
The new AWS Free Tier features are generally available in all AWS Regions, except the AWS GovCloud (US) Regions and the China Regions. To learn more, visit the AWS Free Tier page and AWS Free Tier Documentation.

Give the new AWS Free Tier a try by signing up today, and send feedback to AWS re:Post for AWS Free Tier or through your usual AWS Support contacts.

— Channy

Monitor and debug event-driven applications with new Amazon EventBridge logging

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/monitor-and-debug-event-driven-applications-with-new-amazon-eventbridge-logging/

Starting today, you can use enhanced logging capability in Amazon EventBridge to monitor and debug your event-driven applications with comprehensive logs. These new enhancements help improve how you monitor and troubleshoot event flows.

Here’s how you can find this new capability on the Amazon EventBridge console:

The new observability capabilities address microservices and event-driven architecture monitoring challenges by providing comprehensive event lifecycle tracking. EventBridge now generates detailed log entries every time a matched event against rules is published, delivered to subscribers, or encounters failures and retries.

You gain visibility into the complete event journey with detailed information about successes, failures, and status codes that make identifying and diagnosing issues straightforward. What used to take hours of trial-and-error debugging now takes minutes with detailed event lifecycle tracking and built-in query tools.

Using Amazon EventBridge enhanced observability
Let me walk you through a demonstration that showcases the logging capability in Amazon EventBridge.

I can enable logging for an existing event bus or when creating a new custom event bus. First, I navigate to the EventBridge console and choose Event buses in the left navigation pane. In Custom event bus, I choose Create event bus.

I can see this new capability in the Logs section. I have three options to configure the Log destination: Amazon CloudWatch Logs, Amazon Data Firehose Stream, and Amazon Simple Storage Service (Amazon S3). If I want to stream my logs into a data lake, I can select Amazon Kinesis Data Firehose Stream. Logs are encrypted in transit with TLS and at rest if a customer-managed key (CMK) is provided for the event bus. CloudWatch Logs supports customer-managed keys, and Data Firehose offers server-side encryption for downstream destinations.

For this demo, I select CloudWatch logs and S3 logs.

I can also choose Log level, from Error, Info, or Trace. I choose Trace and select Include execution data because I need to review the payloads. You need to be mindful as logging payload data may contain sensitive information, and this setting applies to all log destinations you select. Then, I configure two destinations, one each for CloudWatch log group and S3 logs. Then I choose Create.

After logging is enabled, I can start publishing test events to observe the logging behavior.

For the first scenario, I’ve built an AWS Lambda function and configured this Lambda function as a target.

I navigate to my event bus to send a sample event by choosing Send events.

Here’s the payload that I use:

{
  "Source": "ecommerce.orders",
  "DetailType": "Order Placed",
  "Detail": {
    "orderId": "12345",
    "customerId": "cust-789",
    "amount": 99.99,
    "items": [
      {
        "productId": "prod-456",
        "quantity": 2,
        "price": 49.99
      }
    ]
  }
}

After I sent the sample event, I can see the logs are available in my S3 bucket.

I can also see the log entries appearing in the Amazon CloudWatch logs. The logs show the event lifecycle, from EVENT_RECEIPT to SUCCESS. Learn more about the complete event lifecycle on TBD:DOC_PAGE.

Now, let’s evaluate these logs. For brevity, I only include a few logs and have redacted them for readability. Here’s the log from when I triggered the event:

{
    "resource_arn": "arn:aws:events:us-east-1:123:event-bus/demo-logging",
    "message_timestamp_ms": 1751608776896,
    "event_bus_name": "demo-logging",
// REDACTED FOR BREVITY //
    "message_type": "EVENT_RECEIPT",
    "log_level": "TRACE",
    "details": {
        "caller_account_id": "123",
        "source_time_ms": 1751608775000,
        "source": "ecommerce.orders",
        "detail_type": "Order Placed",
        "resources": [],
        "event_detail": "REDACTED FOR BREVITY"
    }
}

Here’s the log when the event was successfully invoked:

{
    "resource_arn": "arn:aws:events:us-east-1:123:event-bus/demo-logging",
    "message_timestamp_ms": 1751608777091,
    "event_bus_name": "demo-logging",
// REDACTED FOR BREVITY //
    "message_type": "INVOCATION_SUCCESS",
    "log_level": "INFO",
    "details": {
// REDACTED FOR BREVITY //
        "total_attempts": 1,
        "final_invocation_status": "SUCCESS",
        "ingestion_to_start_latency_ms": 105,
        "ingestion_to_complete_latency_ms": 183,
        "ingestion_to_success_latency_ms": 183,
        "target_duration_ms": 53,
        "target_response_body": "<REDACTED FOR BREVITY>",
        "http_status_code": 202
    }
}

The additional log entries include rich metadata that makes troubleshooting straightforward. For example, on a successful event, I can see the latency timing from starting to completing the event, duration for the target to finish processing, and HTTP status code.

Debugging failures with complete event lifecycle tracking
The benefit of EventBridge logging becomes apparent when things go wrong. To test failure scenarios, I intentionally misconfigure a Lambda function’s permissions and change the rule to point to a different Lambda function without proper permissions.

The attempt failed with a permanent failure due to missing permissions. The log shows it’s a FIRST attempt that resulted in NO_PERMISSIONS status.

{
    "message_type": "INVOCATION_ATTEMPT_PERMANENT_FAILURE",
    "log_level": "ERROR",
    "details": {
        "rule_arn": "arn:aws:events:us-east-1:123:rule/demo-logging/demo-order-placed",
        "role_arn": "arn:aws:iam::123:role/service-role/Amazon_EventBridge_Invoke_Lambda_123",
        "target_arn": "arn:aws:lambda:us-east-1:123:function:demo-evb-fail",
        "attempt_type": "FIRST",
        "attempt_count": 1,
        "invocation_status": "NO_PERMISSIONS",
        "target_duration_ms": 25,
        "target_response_body": "{\"requestId\":\"a4bdfdc9-4806-4f3e-9961-31559cb2db62\",\"errorCode\":\"AccessDeniedException\",\"errorType\":\"Client\",\"errorMessage\":\"User: arn:aws:sts::123:assumed-role/Amazon_EventBridge_Invoke_Lambda_123/db4bff0a7e8539c4b12579ae111a3b0b is not authorized to perform: lambda:InvokeFunction on resource: arn:aws:lambda:us-east-1:123:function:demo-evb-fail because no identity-based policy allows the lambda:InvokeFunction action\",\"statusCode\":403}",
        "http_status_code": 403
    }
}

The final log entry summarizes the complete failure with timing metrics and the exact error message.

{
    "message_type": "INVOCATION_FAILURE",
    "log_level": "ERROR",
    "details": {
        "rule_arn": "arn:aws:events:us-east-1:123:rule/demo-logging/demo-order-placed",
        "role_arn": "arn:aws:iam::123:role/service-role/Amazon_EventBridge_Invoke_Lambda_123",
        "target_arn": "arn:aws:lambda:us-east-1:123:function:demo-evb-fail",
        "total_attempts": 1,
        "final_invocation_status": "NO_PERMISSIONS",
        "ingestion_to_start_latency_ms": 62,
        "ingestion_to_complete_latency_ms": 114,
        "target_duration_ms": 25,
        "http_status_code": 403
    },
    "error": {
        "http_status_code": 403,
        "error_message": "User: arn:aws:sts::123:assumed-role/Amazon_EventBridge_Invoke_Lambda_123/db4bff0a7e8539c4b12579ae111a3b0b is not authorized to perform: lambda:InvokeFunction on resource: arn:aws:lambda:us-east-1:123:function:demo-evb-fail because no identity-based policy allows the lambda:InvokeFunction action",
        "aws_service": "AWSLambda",
        "request_id": "a4bdfdc9-4806-4f3e-9961-31559cb2db62"
    }
}

The logs provide detailed performance metrics that help identify bottlenecks. The ingestion_to_start_latency_ms: 62 shows the time from event ingestion to starting invocation, while ingestion_to_complete_latency_ms: 114 represents the total time from ingestion to completion. Additionally, target_duration_ms: 25 indicates how long the target service took to respond, helping distinguish between EventBridge processing time and target service performance.

The error message clearly states what failed, lambda:InvokeFunction action, why it failed, (no identity-based policy allows the action), which role was involved (Amazon_EventBridge_Invoke_Lambda_1428392416), and which specific resource was affected, which was indicated by the Lambda function Amazon Resource Name (ARN).

Debugging API Destinations with EventBridge Logging
One particular use case that I think EventBridge logging capability will be helpful is to debug issues with API destinations. EventBridge API destinations are HTTPS endpoints that you can invoke as the target of an event bus rule or pipe. HTTPS endpoints help you to route events from your event bus to external systems, software-as-a-service (SaaS) applications, or third-party APIs using HTTPS calls. They use connections to handle authentication and credentials, making it easy to integrate your event-driven architecture with any HTTPS-based service. 

API destinations are commonly used to send events to external HTTPS endpoints and debugging failures from the external endpoint can be a challenge. These problems typically stem from changes to the endpoint authentication requirements or modified credentials.

To demonstrate this debugging capability, I intentionally configured an API destination with incorrect credentials in the connection resource.

When I send an event to this misconfigured endpoint, the enhanced logging shows the root cause of this failure.

{
    "resource_arn": "arn:aws:events:us-east-1:123:event-bus/demo-logging",
    "message_timestamp_ms": 1750344097251,
    "event_bus_name": "demo-logging",
    //REDACTED FOR BREVITY//,
    "message_type": "INVOCATION_FAILURE",
    "log_level": "ERROR",
    "details": {
        //REDACTED FOR BREVITY//,
        "total_attempts": 1,
        "final_invocation_status": "SDK_CLIENT_ERROR",
        "ingestion_to_start_latency_ms": 135,
        "ingestion_to_complete_latency_ms": 549,
        "target_duration_ms": 327,
        "target_response_body": "",
        "http_status_code": 400
    },
    "error": {
        "http_status_code": 400,
        "error_message": "Unable to invoke ApiDestination endpoint: The request failed because the credentials included for the connection are not authorized for the API destination."
    }
}

The log provides immediate clarity about the failure. The target_arn shows this involves an API destination, the final_invocation_status indicates SDK_CLIENT_ERROR, and the http_status_code of 400 , which points to a client-side issue. Most importantly, the error_message explicitly states that: Unable to invoke ApiDestination endpoint: The request failed because the credentials included for the connection are not authorized for the API destination.

This complete log sequence provides useful debugging insights because I can see exactly how the event moved through EventBridge — from event receipt, to ingestion, to rule matching, to invocation attempts. This level of detail eliminates guesswork and points directly to the root cause of the issue.

Additional things to know
Here are a couple of things to note:

  • Architecture support – Logging works with all EventBridge features including custom event buses, partner event sources, and API destinations for HTTPS endpoints.
  • Performance impact – Logging operates asynchronously with no measurable impact on event processing latency or throughput.
  • Pricing – You pay standard Amazon S3, Amazon CloudWatch Logs or Amazon Data Firehose pricing for log storage and delivery. EventBridge logging itself incurs no additional charges. For details, visit the Amazon EventBridge pricing page .
  • Availability – Amazon EventBridge logging capability is available in all AWS Regions where EventBridge is supported.
  • Documentation — For more details, refer to the Amazon EventBridge monitoring and debugging Documentation.

Get started with Amazon EventBridge logging capability by visiting the EventBridge console and enabling logging on your event buses.

Happy building!
— Donnie 

Introducing Amazon S3 Vectors: First cloud storage with native vector support at scale (preview)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-amazon-s3-vectors-first-cloud-storage-with-native-vector-support-at-scale/

Today, we’re announcing the preview of Amazon S3 Vectors, a purpose-built durable vector storage solution that can reduce the total cost of uploading, storing, and querying vectors by up to 90 percent. Amazon S3 Vectors is the first cloud object store with native support to store large vector datasets and provide subsecond query performance that makes it affordable for businesses to store AI-ready data at massive scale.

Vector search is an emerging technique used in generative AI applications to find similar data points to given data by comparing their vector representations using distance or similarity metrics. Vectors are numerical representation of unstructured data created from embedding models. You generate vectors using embedding models for fields inside your document and store vectors into S3 Vectors to search semantically.

S3 Vectors introduces vector buckets, a new bucket type with a dedicated set of APIs to store, access, and query vector data without provisioning any infrastructure. When you create an S3 vector bucket, you organize your vector data within vector indexes, making it simple for running similarity search queries against your dataset. Each vector bucket can have up to 10,000 vector indexes, and each vector index can hold tens of millions of vectors.

After creating a vector index, when adding vector data to the index, you can also attach metadata as key-value pairs to each vector to filter future queries based on a set of conditions, for example, dates, categories, or user preferences. As you write, update, and delete vectors over time, S3 Vectors automatically optimizes the vector data to achieve the best possible price-performance for vector storage, even as the datasets scale and evolve.

S3 Vectors is also natively integrated with Amazon Bedrock Knowledge Bases, including within Amazon SageMaker Unified Studio, for building cost-effective Retrieval-Augmented Generation (RAG) applications. Through its integration with Amazon OpenSearch Service, you can lower storage costs by keeping infrequent queried vectors in S3 Vectors and then quickly move them to OpenSearch as demands increase or to support real-time, low-latency search operations.

With S3 Vectors, you can now economically store the vector embeddings that represent massive amounts of unstructured data such as images, videos, documents, and audio files, enabling scalable generative AI applications including semantic and similarity search, RAG, and build agent memory. You can also build applications to support a wide range of industry use cases including personalized recommendations, automated content analysis, and intelligent document processing without the complexity and cost of managing vector databases.

S3 Vectors in action
To create a vector bucket, choose Vector buckets in the left navigation pane in the Amazon S3 console and then choose Create vector bucket.

Enter a vector bucket name and choose the encryption type. If you don’t specify an encryption type, Amazon S3 applies server-side encryption with Amazon S3 managed keys (SSE-S3) as the base level of encryption for new vectors. You can also choose server-side encryption with AWS Key Management Service (AWS KMS) keys (SSE-KMS). To learn more about managing your vector bucket, visit S3 Vector buckets in the Amazon S3 User Guide.

Now, you can create a vector index to store and query your vector data within your created vector bucket.

Enter a vector index name and the dimensionality of the vectors to be inserted in the index. All vectors added to this index must have exactly the same number of values.

For Distance metric, you can choose either Cosine or Euclidean. When creating vector embeddings, select your embedding model’s recommended distance metric for more accurate results.

Choose Create vector index and then you can insert, list, and query vectors.

To insert your vector embeddings to a vector index, you can use the AWS Command Line Interface (AWS CLI), AWS SDKs, or Amazon S3 REST API. To generate vector embeddings for your unstructured data, you can use embedding models offered by Amazon Bedrock.

If you’re using the latest AWS Python SDKs, you can generate vector embeddings for your text using Amazon Bedrock using following code example:

# Generate and print an embedding with Amazon Titan Text Embeddings V2.
import boto3 
import json 

# Create a Bedrock Runtime client in the AWS Region of your choice. 
bedrock= boto3.client("bedrock-runtime", region_name="us-west-2") 

The text strings to convert to embeddings.
texts = [
"Star Wars: A farm boy joins rebels to fight an evil empire in space", 
"Jurassic Park: Scientists create dinosaurs in a theme park that goes wrong",
"Finding Nemo: A father fish searches the ocean to find his lost son"]

embeddings=[]
#Generate vector embeddings for the input texts
for text in texts:
        body = json.dumps({
            "inputText": text
        })    
        # Call Bedrock's embedding API
        response = bedrock.invoke_model(
        modelId='amazon.titan-embed-text-v2:0',  # Titan embedding model 
        body=body)   
        # Parse response
        response_body = json.loads(response['body'].read())
        embedding = response_body['embedding']
        embeddings.append(embedding)

Now, you can insert vector embeddings into the vector index and query vectors in your vector index using the query embedding:

# Create S3Vectors client
s3vectors_client = boto3.client('s3vectors', region_name='us-west-2')

# Insert vector embedding
s3vectors.put_vectors( vectorBucketName="channy-vector-bucket",
  indexName="channy-vector-index", 
  vectors=[
{"key": "v1", "data": {"float32": embeddings[0]}, "metadata": {"id": "key1", "source_text": texts[0], "genre":"scifi"}},
{"key": "v2", "data": {"float32": embeddings[1]}, "metadata": {"id": "key2", "source_text": texts[1], "genre":"scifi"}},
{"key": "v3", "data": {"float32": embeddings[2]}, "metadata": {"id": "key3", "source_text":  texts[2], "genre":"family"}}
],
)

#Create an embedding for your query input text
# The text to convert to an embedding.
input_text = "List the movies about adventures in space"

# Create the JSON request for the model.
request = json.dumps({"inputText": input_text})

# Invoke the model with the request and the model ID, e.g., Titan Text Embeddings V2. 
response = bedrock.invoke_model(modelId="amazon.titan-embed-text-v2:0", body=request)

# Decode the model's native response body.
model_response = json.loads(response["body"].read())

# Extract and print the generated embedding and the input text token count.
embedding = model_response["embedding"]

# Performa a similarity query. You can also optionally use a filter in your query
query = s3vectors.query_vectors( vectorBucketName="channy-vector-bucket",
  indexName="channy-vector-index",
  queryVector={"float32":embedding},
  topK=3, 
  filter={"genre":"scifi"},
  returnDistance=True,
  returnMetadata=True
  )
results = query["vectors"]
print(results)

To learn more about inserting vectors into a vector index, or listing, querying, and deleting vectors, visit S3 vector buckets and S3 vector indexes in the Amazon S3 User Guide. Additionally, with the S3 Vectors embed command line interface (CLI), you can create vector embeddings for your data using Amazon Bedrock and store and query them in an S3 vector index using single commands. For more information, see the S3 Vectors Embed CLI GitHub repository.

Integrate S3 Vectors with other AWS services
S3 Vectors integrates with other AWS services such as Amazon Bedrock, Amazon SageMaker, and Amazon OpenSearch Service to enhance your vector processing capabilities and provide comprehensive solutions for AI workloads.

Create Amazon Bedrock Knowledge Bases with S3 Vectors
You can use S3 Vectors in Amazon Bedrock Knowledge Bases to simplify and reduce the cost of vector storage for RAG applications. When creating a knowledge base in the Amazon Bedrock console, you can choose the S3 vector bucket as your vector store option.

In Step 3, you can choose the Vector store creation method either to create an S3 vector bucket and vector index or choose the existing S3 vector bucket and vector index that you’ve previously created.

For detailed step-by-step instructions, visit Create a knowledge base by connecting to a data source in Amazon Bedrock Knowledge Bases in the Amazon Bedrock User Guide.

Using Amazon SageMaker Unified Studio
You can create and manage knowledge bases with S3 Vectors in Amazon SageMaker Unified Studio when you build your generative AI applications through Amazon Bedrock. SageMaker Unified Studio is available in the next generation of Amazon SageMaker and provides a unified development environment for data and AI, including building and texting generative AI applications that use Amazon Bedrock knowledge bases.

You can choose your knowledge bases using the S3 Vectors created through Amazon Bedrock when you build generative AI applications. To learn more, visit Add a data source to your Amazon Bedrock app in the Amazon SageMaker Unified Studio User Guide.

Export S3 vector data to Amazon OpenSearch Service
You can balance cost and performance by adopting a tiered strategy that stores long-term vector data cost-effectively in Amazon S3 while exporting high priority vectors to OpenSearch for real-time query performance.

This flexibility means your organizations can access OpenSearch’s high performance (high QPS, low latency) for critical, real-time applications, such as product recommendations or fraud detection, while keeping less time-sensitive data in S3 Vectors.

To export your vector index, choose Advanced search export, then choose Export to OpenSearch in the Amazon S3 console.

Then, you will be brought to the Amazon OpenSearch Service Integration console with a template for S3 vector index export to OpenSearch vector engine. Choose Export with pre-selected S3 vector source and a service access role.

It will start the steps to create a new OpenSearch Serverless collection and migrate data from your S3 vector index into an OpenSearch knn index.

Choose the Import history in the left navigation pane. You can see the new import job that was created to make a copy of vector data from your S3 vector index into the OpenSearch Serverless collection.

Once the status changes to Complete, you can connect to the new OpenSearch serverless collection and query your new OpenSearch knn index.

To learn more, visit Creating and managing Amazon OpenSearch Serverless collections in the Amazon OpenSearch Service Developer Guide.

Now available
Amazon S3 Vectors, and its integrations with Amazon Bedrock, Amazon OpenSearch Service, and Amazon SageMaker are now in preview in the US East (N. Virginia), US East (Ohio), US West (Oregon), Europe (Frankfurt), and Asia Pacific (Sydney) Regions.

Give S3 Vectors a try in the Amazon S3 console today and send feedback to AWS re:Post for Amazon S3 or through your usual AWS Support contacts.

— Channy

Amazon S3 Metadata now supports metadata for all your S3 objects

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-s3-metadata-now-supports-metadata-for-all-your-s3-objects/

Amazon S3 Metadata now provides complete visibility into all your existing objects in your Amazon Simple Storage Service (Amazon S3) buckets, expanding beyond new objects and changes. With this expanded coverage, you can analyze and query metadata for your entire S3 storage footprint.

Today, many customers rely on Amazon S3 to store unstructured data at scale. To understand what’s in a bucket, you often need to build and maintain custom systems that scan for objects, track changes, and manage metadata over time. These systems are expensive to maintain and hard to keep up to date as data grows.

Since the launch of S3 Metadata at re:Invent 2024, you’ve been able to query new and updated object metadata using metadata tables instead of relying on Amazon S3 Inventory or object-level APIs such as ListObjects, HeadObject, and GetObject—which can introduce latency and impact downstream workflows.

To make it easier for you to work with this expanded metadata, S3 Metadata introduces live inventory tables that work with familiar SQL-based tools. After your existing objects are backfilled into the system, any updates like uploads or deletions typically appear within an hour in your live inventory tables.

With S3 Metadata live inventory tables, you get a fully managed Apache Iceberg table that provides a complete and current snapshot of the objects and their metadata in your bucket, including existing objects, thanks to backfill support. These tables are refreshed automatically within an hour of changes such as uploads or deletions, so you stay up to date. You can use them to identify objects with specific properties—like unencrypted data, missing tags, or particular storage classes—and to support analytics, cost optimization, auditing, and governance.

S3 Metadata journal tables, previously known as S3 Metadata tables, are automatically enabled when you configure live inventory tables, provide a near real-time view of object-level changes in your bucket—including uploads, deletions, and metadata updates. These tables are ideal for auditing activity, tracking the lifecycle of objects, and generating event-driven insights. For example, you can use them to find out which objects were deleted in the past 24 hours, identify the requester making the most PUT operations, or monitor updates to object metadata over time.

S3 Metadata tables are created in a namespace name that is similar to your bucket name for easier discovery. The tables are stored in AWS system table buckets, grouped by account and Region. After you enable S3 Metadata for a general purpose S3 bucket, the system creates and maintains these tables for you. You don’t need to manage compaction or garbage collection processes—S3 Tables takes care of table maintenance tasks in the background.

These new tables help avoid waiting for metadata discovery before processing can begin, making them ideal for large-scale analytics and machine learning (ML) workloads. By querying metadata ahead of time, you can schedule GPU jobs more efficiently and reduce idle time in compute-intensive environments.

Let’s see how it works
To see how this works in practice, I configure S3 Metadata for a general purpose bucket using the AWS Management Console.

S3 Metadata, start from general purpose bucket

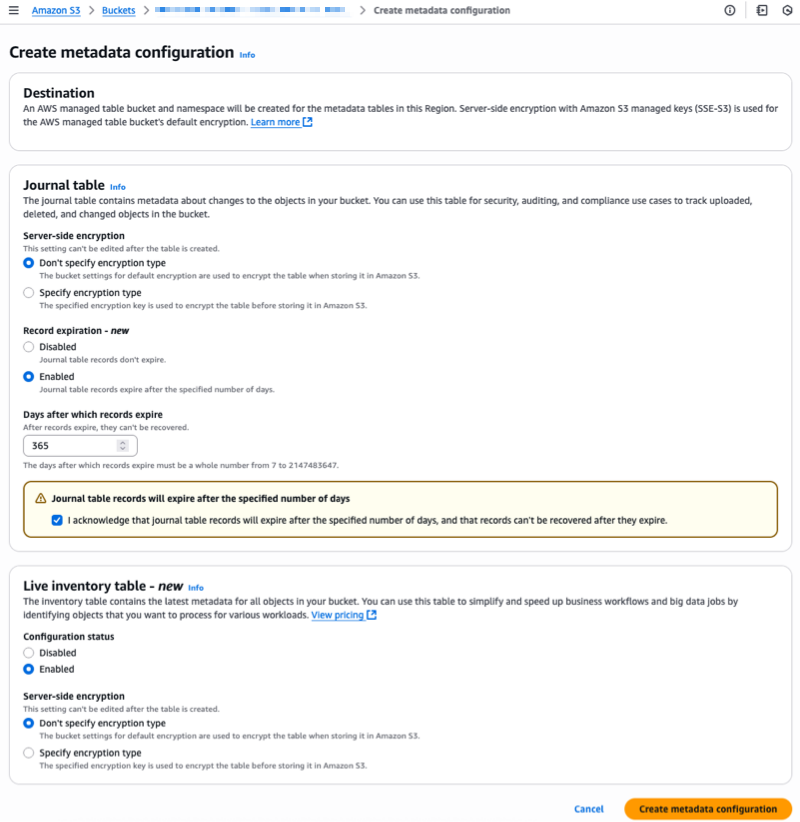
After choosing a general purpose bucket, I choose the Metadata tab, then I choose Create metadata configuration.

S3 Metadata, configure journal and inventory tableFor Journal table, I can choose the Server-side encryption option and the Record expiration period. For Live Inventory table, I choose Enabled and I can select the Server-side encryption options.

I configure Record expiration on the journal table. Journal table records expire after the specified number of days, 365 days (one year) in my example.

Then, I choose Create metadata configuration.

S3 Metadata, backfilling

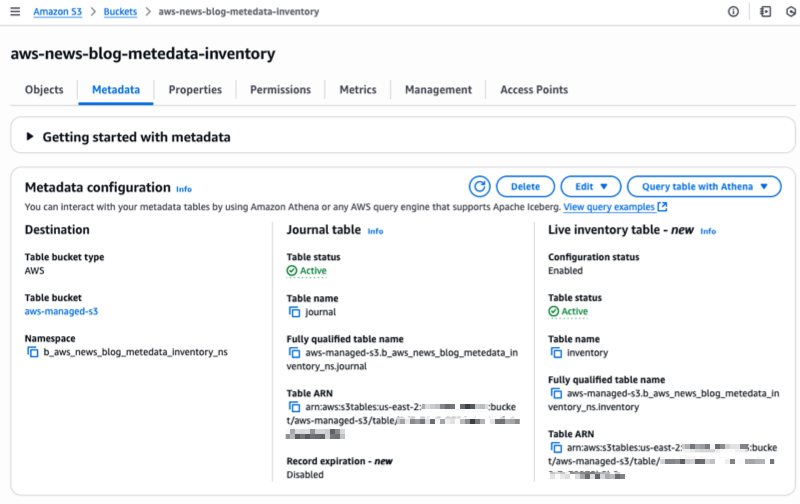
S3 Metadata creates the live inventory table and journal table. In the Live Inventory table section, I can observe the Table status: the system immediately starts to backfill the table with existing object metadata. It can take between minutes to hours. The exact time depends on the quantity of objects you have in your S3 bucket.

While waiting, I also upload and delete objects to generate data in the journal table.

Then, I navigate to Amazon Athena to start querying the new tables.

S3 Metadata, query with Athena

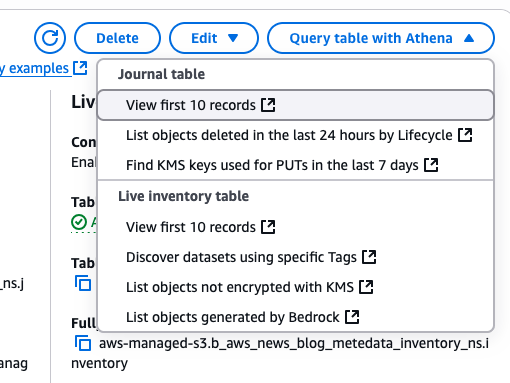
I choose Query table with Athena to start querying the table. I can choose between a couple of default queries on the console.

S3 MetaData table structure

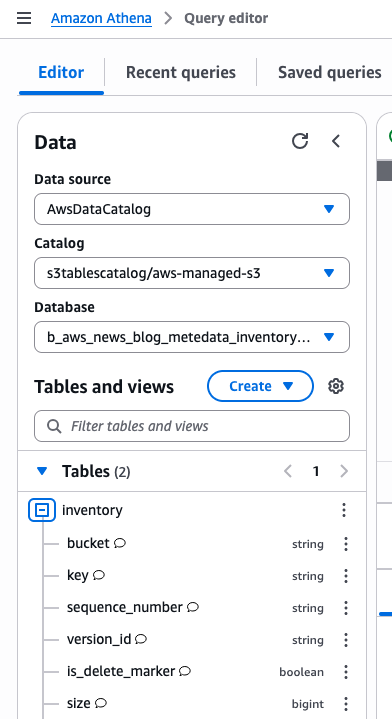
In Athena, I observe the structure of the tables in the AWSDataCatalog Data source and I start with a short query to check how many records are available in the journal table. I already have 6,488 entries:

SELECT count(*) FROM "b_aws_news_blog_metadata_inventory_ns"."journal";

# _col0
1 6488

Here are a couple of example queries I tried on the journal table:

# Query deleted objects in last 24 hours
# Use is_delete_marker=true for versioned buckets and record_type='DELETE' otherwise
SELECT bucket, key, version_id, last_modified_date
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."journal"
WHERE last_modified_date >= (current_date - interval '1' day) AND is_delete_marker = true;

# bucket key version_id last_modified_date is_delete_marker
1 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G0/NSURLSession.h-JET61D329FG0 
2 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G5/cdefs.h-PJ21EUWKMWG5 
3 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/FX/buf.h-25EDY57V6ZXFX 
4 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G6/NSMeasurementFormatter.h-3FN8J9CLVMYG6 
5 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G8/NSXMLDocument.h-1UO2NUJK0OAG8 

# Query recent PUT requests IP addresses
SELECT source_ip_address, count(source_ip_address)
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."journal"
GROUP BY source_ip_address;

#	source_ip_address	_col1
1	my_laptop_IP_address	12488

# Query S3 Lifecycle expired objects in last 7 days
SELECT bucket, key, version_id, last_modified_date, record_timestamp
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."journal"
WHERE requester = 's3.amazonaws.com' AND record_type = 'DELETE' AND record_timestamp > (current_date - interval '7' day);

(not applicable to my demo bucket)

The results helped me track the specific objects that were removed, including their timestamps.

Now, I look at the live inventory table:

# Distribution of object tags
SELECT object_tags, count(object_tags)
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."inventory"
GROUP BY object_tags;

# object_tags    _col1
1 {Source=Swift} 1
2 {Source=swift} 1
3 {}             12486

# Query storage class and size for specific tags
SELECT storage_class, count(*) as count, sum(size) / 1024 / 1024 as usage
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."inventory"
GROUP BY object_tags['pii=true'], storage_class;

# storage_class count   usage
1 STANDARD      124884  165

# Find objects with specific user defined metadata
SELECT key, last_modified_date, user_metadata
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."inventory"
WHERE cardinality(user_metadata) > 0 ORDER BY last_modified_date DESC;

(not applicable to my demo bucket)

These are just a few examples of what is possible with S3 Metadata. Your preferred queries will depend on your use cases. Refer to Analyzing Amazon S3 Metadata with Amazon Athena and Amazon QuickSight in the AWS Storage Blog for more examples.

Pricing and availability
S3 Metadata live inventory and journal tables are available today in US East (Ohio, N. Virginia) and US West (N. California).

The journal tables are charged $0.30 per million updates. This is a 33 percent drop from our previous price.

For inventory tables, there’s a one-time backfill cost of $0.30 for a million objects to set up the table and generate metadata for existing objects. There are no additional costs if your bucket has less than one billion objects. For buckets with more than a billion objects, there is a monthly fee of $0.10 per million objects per month.

As usual, the Amazon S3 pricing page has all the details.

With S3 Metadata live inventory and journal tables, you can reduce the time and effort required to explore and manage large datasets. You get an up-to-date view of your storage and a record of changes, and both are available as Iceberg tables you can query on demand. You can discover data faster, power compliance workflows, and optimize your ML pipelines.

You can get started by enabling metadata inventory on your S3 bucket through the AWS console, AWS Command Line Interface (AWS CLI), or AWS SDKs. When they’re enabled, the journal and live inventory tables are automatically created and updated. To learn more, visit the S3 Metadata Documentation page.

— seb

TwelveLabs video understanding models are now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/twelvelabs-video-understanding-models-are-now-available-in-amazon-bedrock/

Earlier this year, we preannounced that TwelveLabs video understanding models were coming to Amazon Bedrock. Today, we’re announcing the models are now available for searching through videos, classifying scenes, summarizing, and extracting insights with precision and reliability.

TwelveLabs has introduced Marengo, a video embedding model proficient at performing tasks such as search and classification, and Pegasus, a video language model that can generate text based on video data. These models are trained on Amazon SageMaker HyperPod to deliver groundbreaking video analysis that provides text summaries, metadata generation, and creative optimization.

With the TwelveLabs models in Amazon Bedrock, you can find specific moments using natural language video search capabilities like “show me the first touchdown of the game” or “find the scene where the main characters first meet” and instantly jump to those exact moments. You can also build applications to understand video content by generating descriptive text such as titles, topics, hashtags, summaries, chapters, or highlights for discovering insights and connections without requiring predefined labels or categories.

For example, you can find recurring themes in customer feedback or spot product usage patterns that weren’t obvious before. Whether you have hundreds or thousands of hours of video content, you can now transform that entire library into a searchable knowledge resource while maintaining enterprise-grade security and performance.

Let’s take a look at the Marengo and Pegasus videos that TwelveLabs has published.

You can transform video workflows with these models across industries. Media producers and editors can instantly locate specific scenes or dialogue, which means you can focus on storytelling rather than sifting through hours of footage. Marketing teams are streamlining their advertising workflows by quickly personalizing content to resonate with various audiences, while security teams are using the technology to proactively identify potential risks by spotting patterns across multiple video feeds.

Getting started with TwelveLabs models in Amazon Bedrock
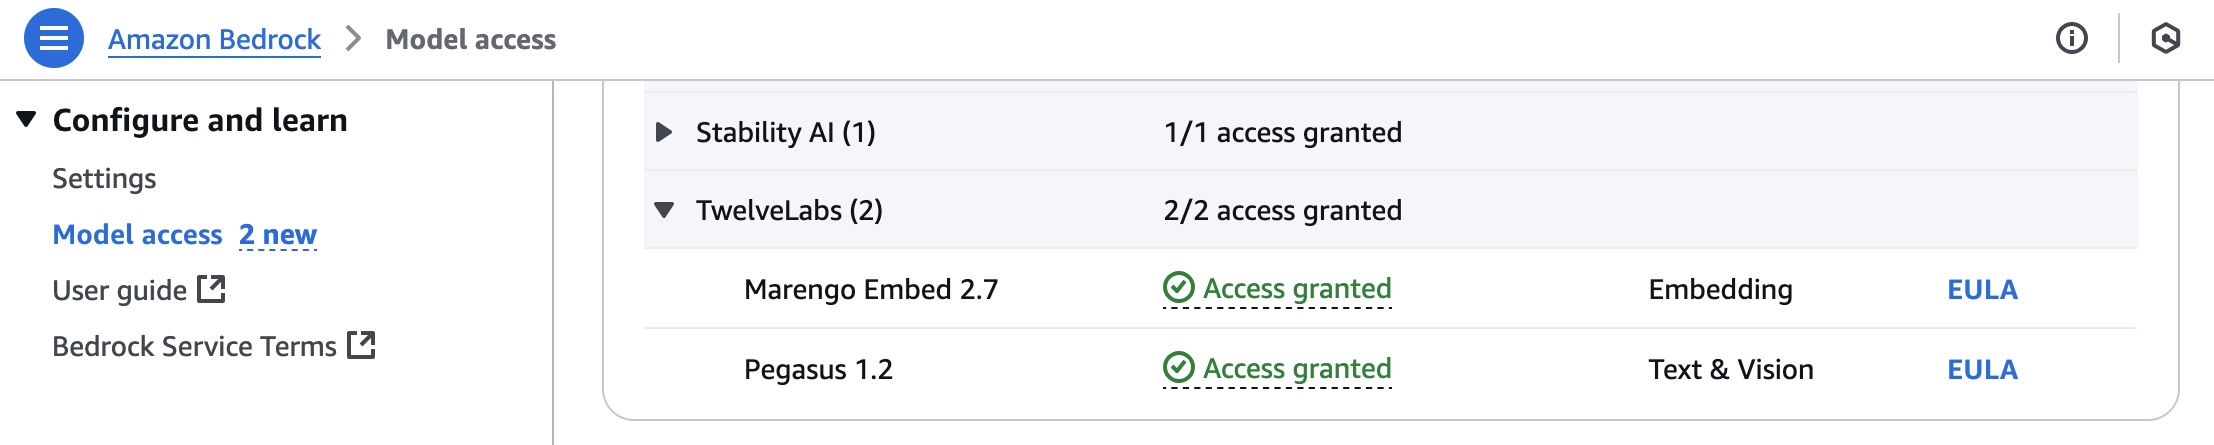
Before getting started, if you’re new to using TwelveLabs models, go to the Amazon Bedrock console and choose Model access in the bottom left navigation pane. To access the latest TwelveLabs models, request access for Marengo Embed 2.7 and Pegasus 1.2 in TwelveLabs.

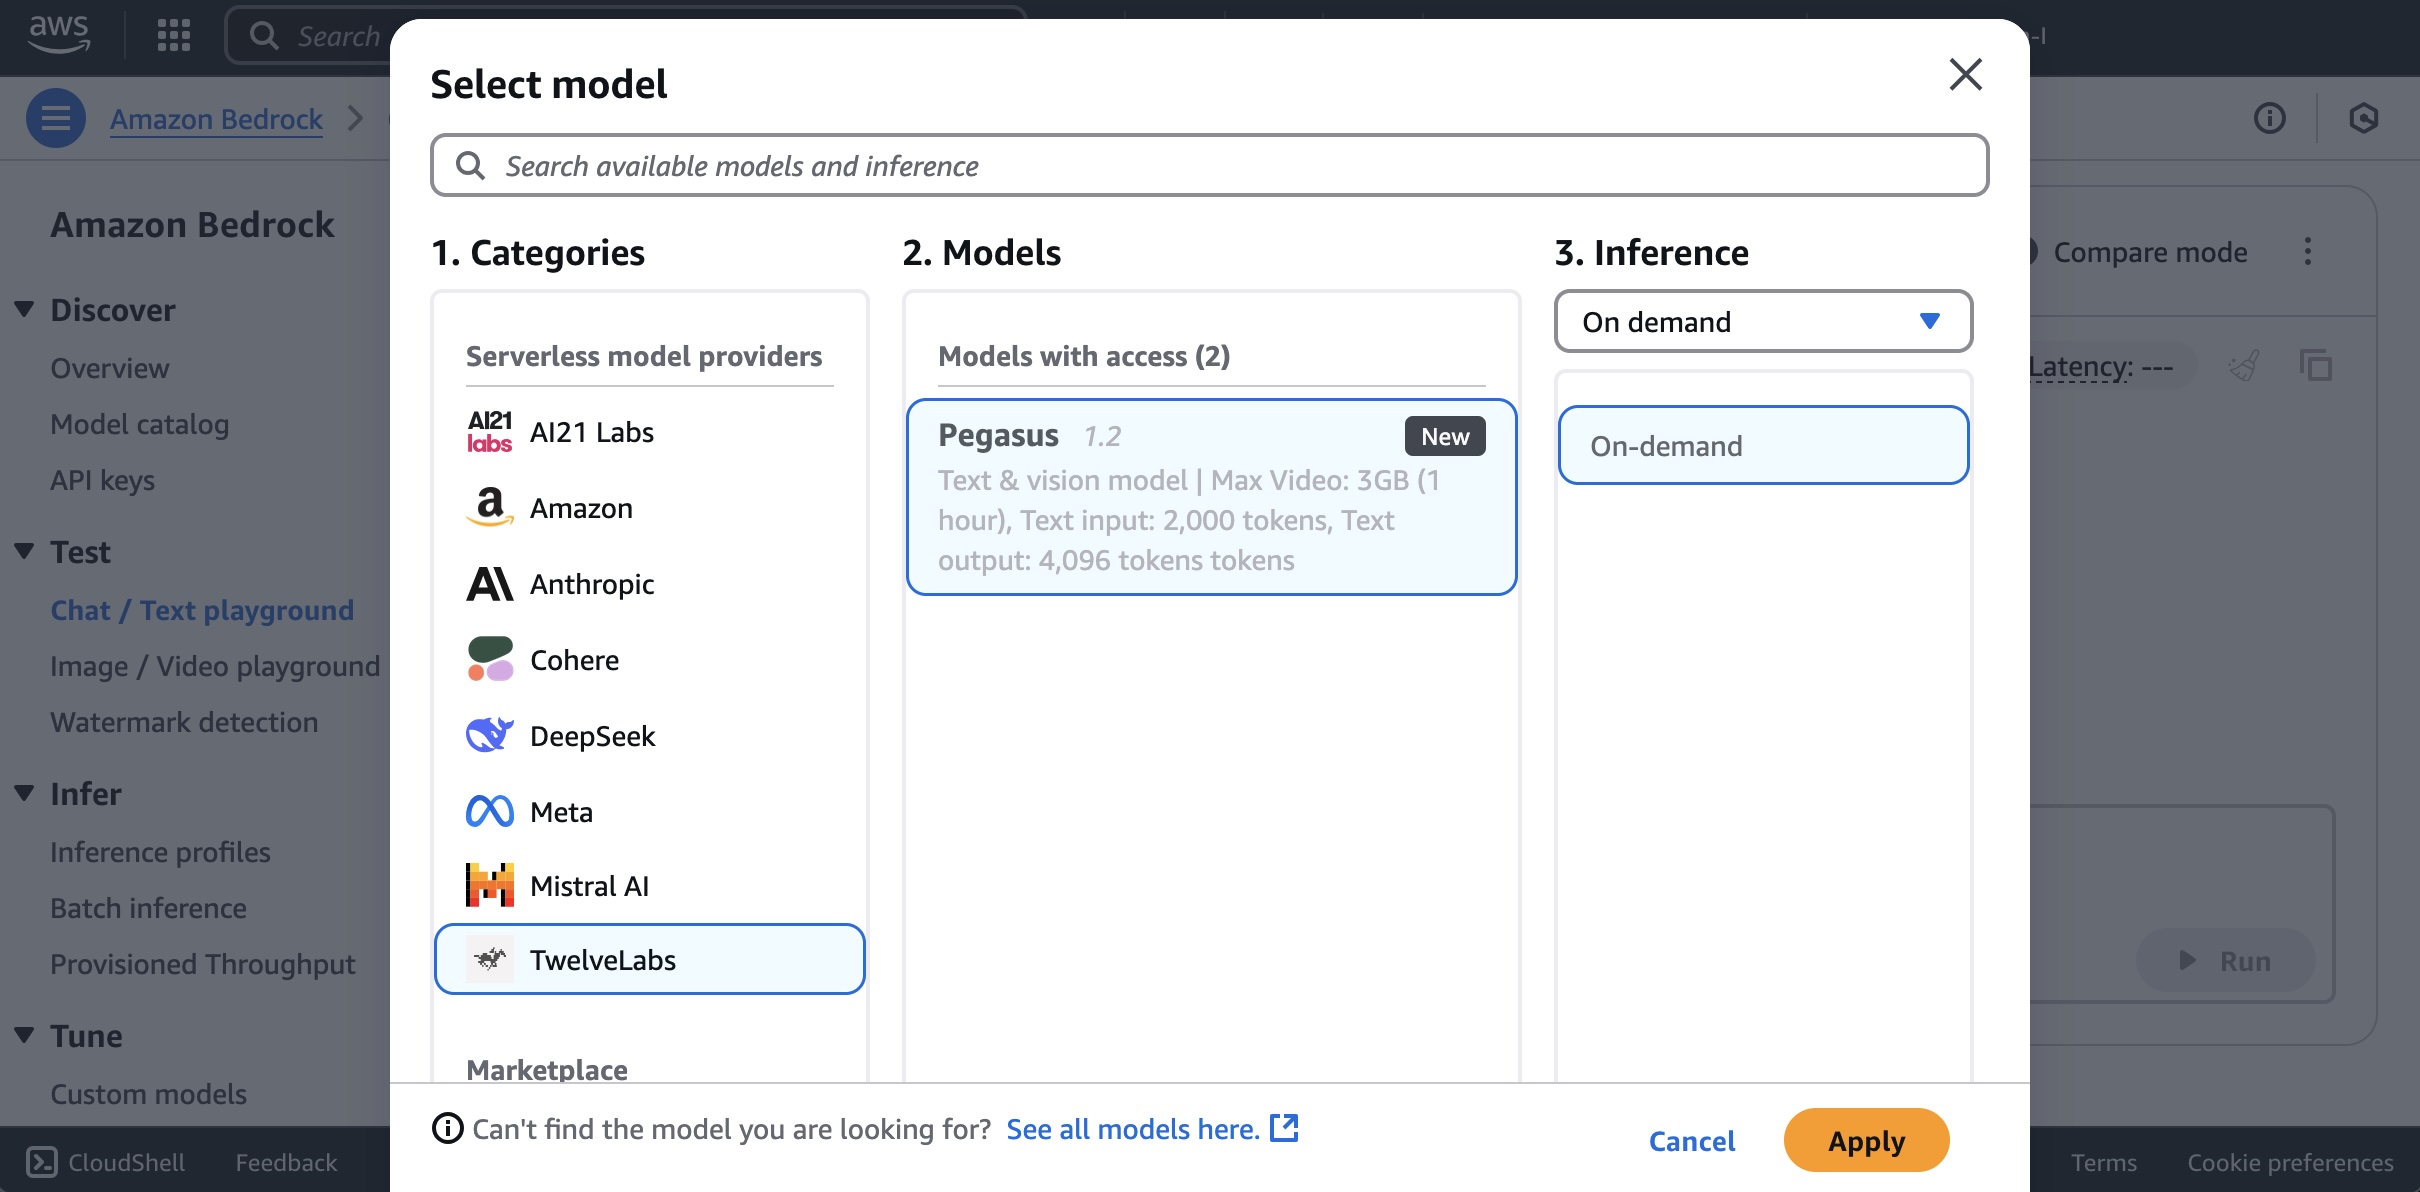
To use TwelveLabs models in Amazon Bedrock, choose Chat/Text Playground under Test in the left navigation pane. Choose Select model, select TwelveLabs as the category and Pegasus as the model, and then choose Apply.

For searching or generating text from your video, you should upload your video to an Amazon Simple Storage Service (Amazon S3) bucket or input Base64-formatted video string.

I will use a sample video generated with Amazon Nova Reel with a prompt: “A cute raccoon playing guitar underwater.”

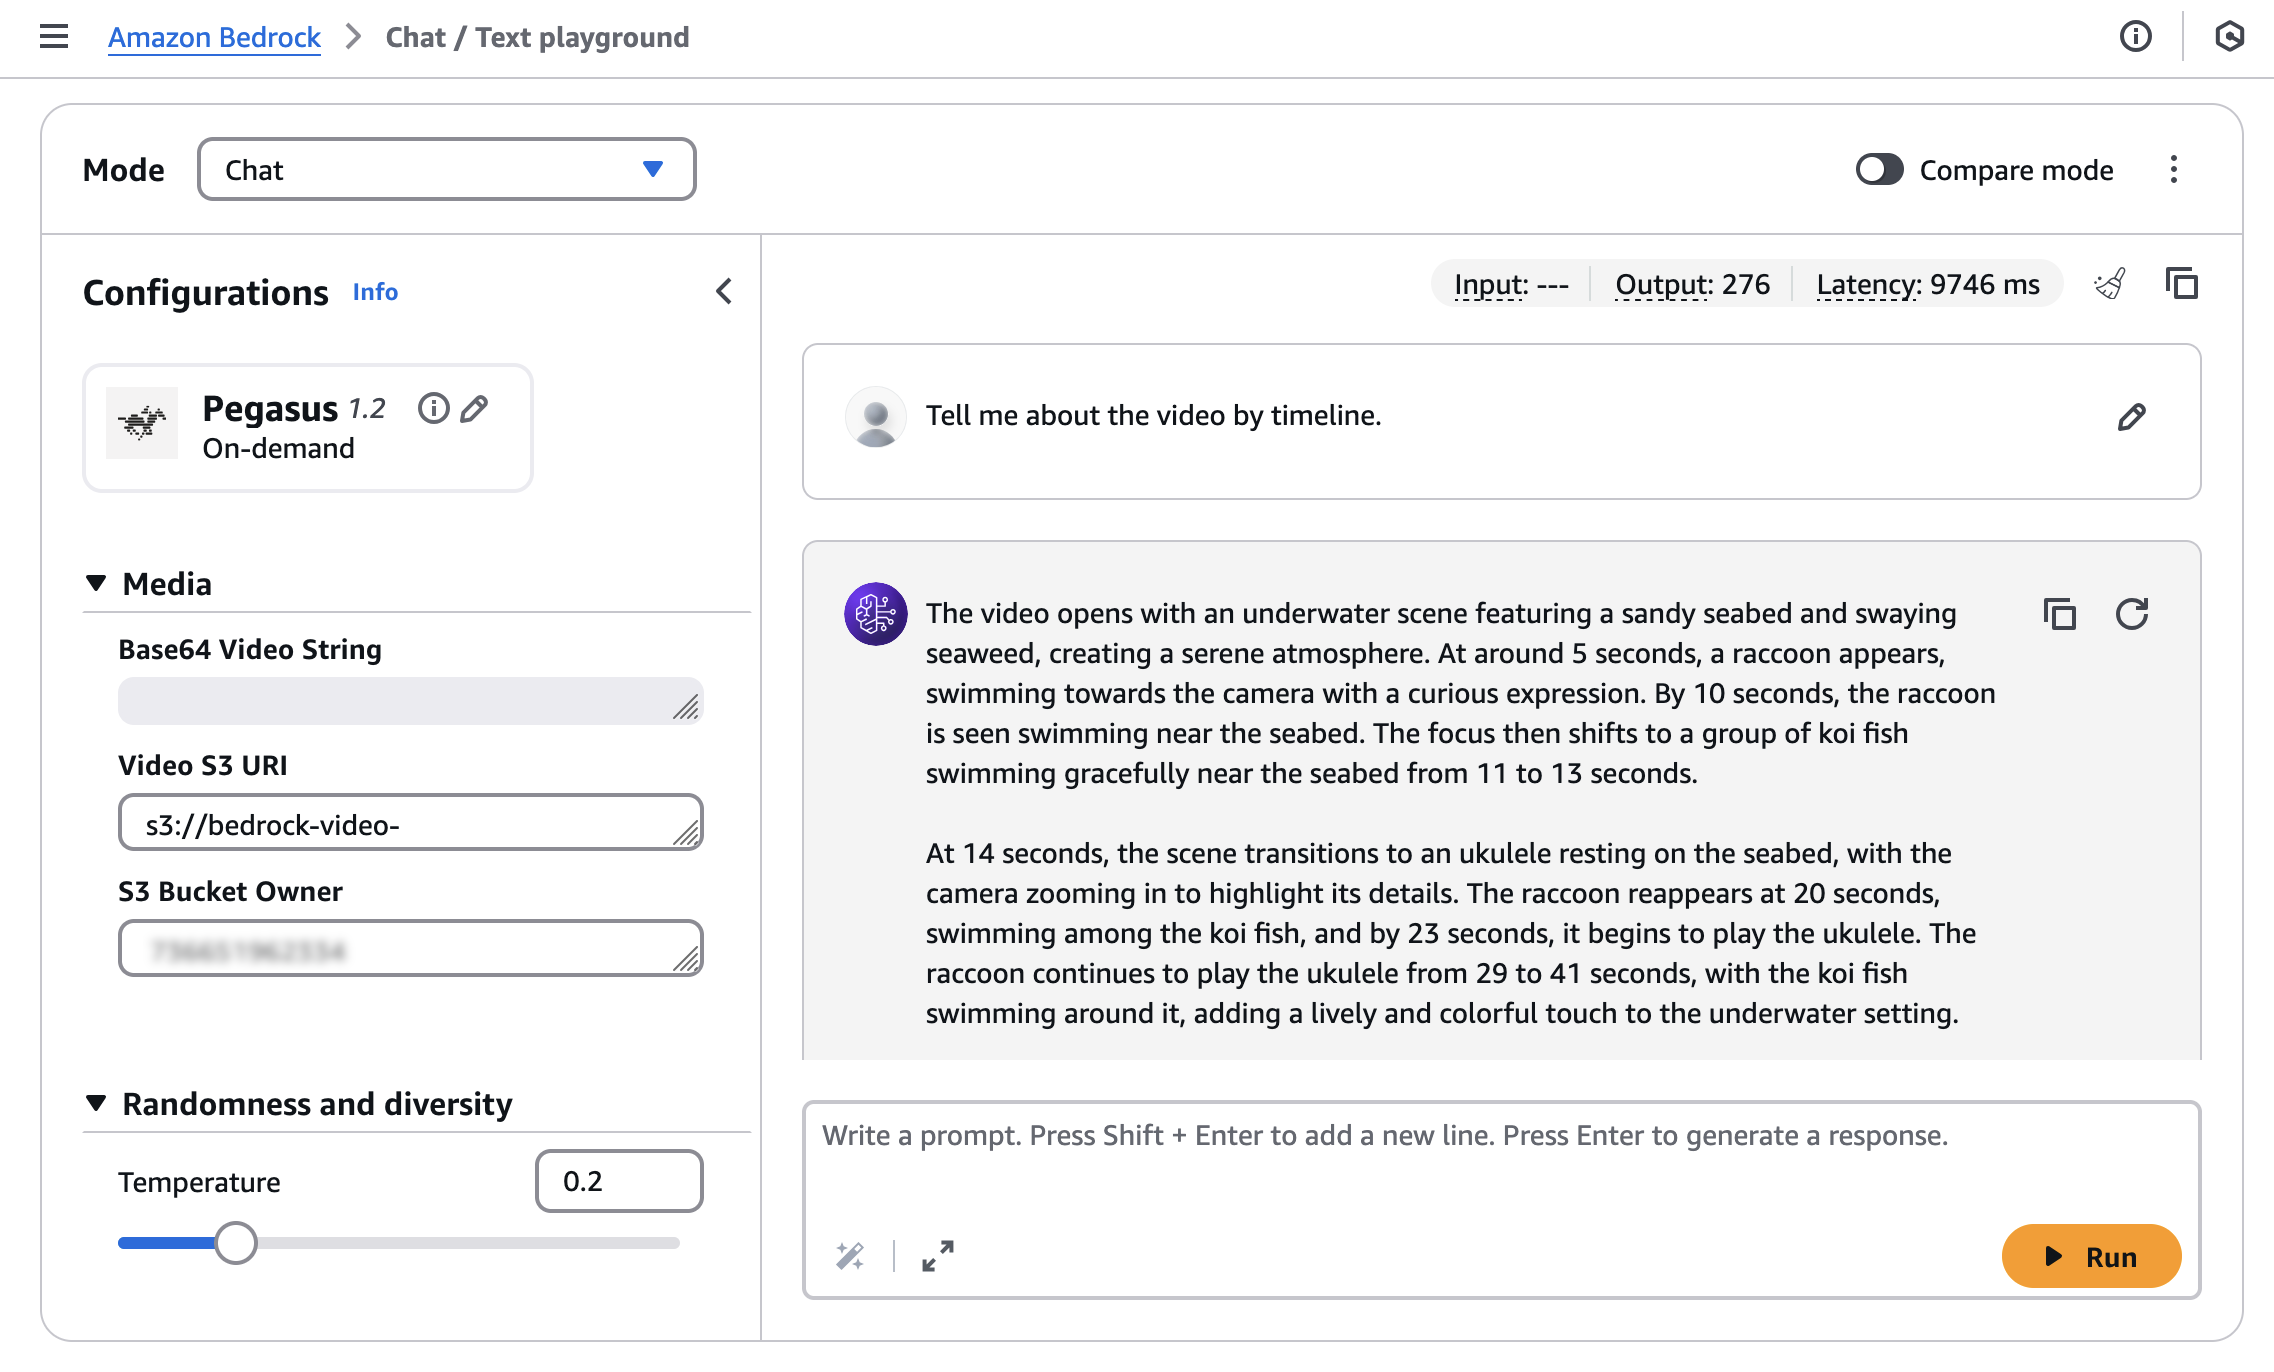
Enter the S3 URI of your uploaded video and the S3 Bucket Owner, and then run your prompt: “Tell me about the video by timeline”.

You can get following model response:

The video opens with an underwater scene featuring a sandy seabed and swaying seaweed, creating a serene atmosphere. At around 5 seconds, a raccoon appears, swimming towards the camera with a curious expression. By 10 seconds, the raccoon is seen swimming near the seabed. The focus then shifts to a group of koi fish swimming gracefully near the seabed from 11 to 13 seconds.

At 14 seconds, the scene transitions to an ukulele resting on the seabed, with the camera zooming in to highlight its details. The raccoon reappears at 20 seconds, swimming among the koi fish, and by 23 seconds, it begins to play the ukulele. The raccoon continues to play the ukulele from 29 to 41 seconds, with the koi fish swimming around it, adding a lively and colorful touch to the underwater setting.

From 42 to 49 seconds, the raccoon is shown playing the ukulele with the koi fish swimming around it. The video concludes with a screen displaying "Video generated with Amazon Novo Reel 1.1" and "Available in Amazon Bedrock" from 50 to 54 seconds, followed by the AWS logo from 55 to 57 seconds.

The TwelveLabs models can be easily integrated into your applications using the Amazon Bedrock Converse API, which provides a unified interface for conversational AI interactions.

Here’s an example of how to use the AWS SDK for Python (Boto3) with the TwelveLabs Pegasus model:

import boto3
import json
import os

AWS_REGION = "us-east-1"
MODEL_ID = "twelvelabs.pegasus-1-2-v1:0"
VIDEO_PATH = "sample.mp4"

def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

bedrock_runtime = boto3.client(
    service_name="bedrock-runtime",
    region_name=AWS_REGION
)

request_body = {
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "inputPrompt": "tell me about the video",
                    "mediaSource: {
                        "base64String": read_file(VIDEO_PATH)
                    }
                },
            ],
        }
    ]
}

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=request_body["messages"]
)

print(response["output"]["message"]["content"][-1]["text"])

The TwelveLabs Marengo Embed 2.7 model generates vector embeddings from video, text, audio, or image inputs. These embeddings can be used for similarity search, clustering, and other machine learning (ML) tasks. The model supports asynchronous inference through the Bedrock AsyncInvokeModel API.

For video source, you can request JSON format for the TwelveLabs Marengo Embed 2.7 model using the AsyncInvokeModel API.

{
    "modelId": "twelvelabs.marengo-embed-2.7",
    "modelInput": {
        "inputType": "video",
        "mediaSource": {
            "s3Location": {
                "uri": "s3://your-video-object-s3-path",
                "bucketOwner": "your-video-object-s3-bucket-owner-account"
            }
        }
    },
    "outputDataConfig": {
        "s3OutputDataConfig": {
            "s3Uri": "s3://your-bucket-name"
        }
    }
}

You can get a response delivered to the specified S3 location.

{
    "embedding": [0.345, -0.678, 0.901, ...],
    "embeddingOption": "visual-text",
    "startSec": 0.0,
    "endSec": 5.0
}

To help you get started, check out a broad range of code examples for multiple use cases and a variety of programming languages. To learn more, visit TwelveLabs Pegasus 1.2 and TwelveLabs Marengo Embed 2.7 in the AWS Documentation.

Now available
TwelveLabs models are generally available today in Amazon Bedrock: the Marengo model in the US East (N. Virginia), Europe (Ireland), and Asia Pacific (Seoul) Region, and the Pegasus model in US West (Oregon), and Europe (Ireland) Region accessible with cross-Region inference from US and Europe Regions. Check the full Region list for future updates. To learn more, visit the TwelveLabs in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give TwelveLabs models a try on the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: AWS Builder Center, Amazon Q, Oracle Database@AWS, and more (July 14, 2025)

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-builder-center-amazon-q-oracle-databaseaws-and-more-july-14-2025/

Summer is well and truly here in the UK! I’m a bit of a summer grinch though so, unlike most people, I’m not crazy about “the glorious sun” scorching me when I’m out and about. On the upside, this provides the perfect excuse to retreat to the comfort of a well-ventilated room where I can focus on coding and curating the latest AWS releases to bring you the highlights.

I also managed to escape the heat for most of yesterday while recording an episode for the AWS Developers Podcast where the wonderful Sebastien Stormaq and Tiffany Souterre interviewed me about games development. If you haven’t discovered it yet, I highly recommend you give it a go as the episodes are full of interesting lessons and insights from not just AWS, but customers and community members who share their stories and expertise in a relaxed conversation.

Alright, ready to discover some of the new things we released last week? Here are the highlights.

AWS Builder Center
There is a new home for AWS builders and community members! AWS Builder Center is a new place where cloud builders can connect, share knowledge, and access resources to enhance their AWS journey. The platform enables users to join community programs, discover trending topics, access AWS Skill Builder courses, participate in technical challenges, and more, using a single Builder ID sign-in.

One the features that I’m personally most excited about is the Wishlist. You can now create wishes and tell AWS directly about ways to improve our products and services or share original ideas that you think could help you and your teams. You can also browse and upvote existing wishes to support any suggestions that you think should be prioritized. The AWS teams will keep an eye on this and if a wish has enough traction it may just be considered!

Read the news blog post for a quick tour through some of the most exciting features or head over to AWS Builder Center and start exploring!

AI
The world of AI keeps moving fast and changing our world, by providing new and exciting ways to do things and become more productive. Here are two releases from last week that caught my attention.

  • Amazon Q chat in the AWS Management Console can now query AWS service data – Amazon Q Developer expands its capabilities by enabling natural language queries of data stored across AWS services like S3, DynamoDB, and CloudWatch, directly from the AWS Console, Slack, Microsoft Teams, and AWS Console Mobile Application. This enhancement streamlines cloud management and troubleshooting by allowing users to access and analyze service data through conversational interfaces, with access controls managed through IAM permissions.
  • Amazon CloudWatch and Application Signals MCP servers for AI-assisted troubleshooting – AWS has released two new Model Context Protocol (MCP) servers – CloudWatch MCP and Application Signals MCP – that enable AI agents to leverage observability data for automated troubleshooting through conversational interfaces. These open-source servers allow AI assistants to analyze metrics, alarms, logs, traces, and service health data across AWS environments, streamlining incident response and root cause analysis without requiring developers to manually navigate multiple AWS consoles.

Oracle Database@AWS
It seems like yesterday when Andy Jassy announced our partnership with Oracle to create Oracle Database@AWS, a jointly offered service that runs Oracle databases on Exadata infrastructure directly within AWS data centers, providing a unified AWS-Oracle experience. Fast forward to last week and Oracle Database@AWS has reached a significant milestone with its general availability release. It is now available in US East (N. Virginia) and US West (Oregon) regions, with plans to expand to 20 additional regions globally.

In addition, VPC Lattice has added support for Oracle Database@AWS enabling seamless connectivity between applications in VPCs and on-premises environments to Oracle database networks. The integration simplifies network management and provides secure access from Oracle Database@AWS to AWS services like Amazon S3 and Amazon Redshift, without requiring complex networking setup.

So if you’re looking to migrate your Oracle database workloads, now is a great time to explore Oracle Database@AWS as it offers a compelling path forward with minimal modifications required.

Additional highlights
Here are some other releases that I think many people will be happy about.

  • AWS Config now supports 12 new resource types – AWS Config has expanded its monitoring capabilities with support for 12 new resource types across services including BackupGateway, CloudFront, EntityResolution, Bedrock, and more. These additions are automatically tracked if you have enabled recording for all resource types, enhancing your ability to discover, assess, and audit AWS resources.
  • Amazon SageMaker Studio now supports remote connections from Visual Studio Code – Amazon SageMaker Studio now supports remote connections from Visual Studio Code, allowing developers to use their familiar VS Code setup while leveraging SageMaker’s scalable compute resources for AI development.
  • AWS Network Firewall: Native AWS Transit Gateway support in all regions – AWS Network Firewall now offers native integration with AWS Transit Gateway across all supported regions, enabling direct attachment and simplified traffic inspection between VPCs and on-premises networks. This integration eliminates the need for managing dedicated VPC subnets and route tables while providing multi-AZ redundancy for improved security and reliability.

Upcoming AWS Events
AWS Summit New York – this is definitely one to watch…literally! Registrations are closed due to capacity but you can tune in to watch live all the announcements and launches! No spoilers, but, trust me, there are a quite a few exciting things in store, so make sure to check it out.

AWS Gen AI Lofts – AWS Gen AI Lofts are multi-day events offering hands-on workshops, expert guidance, and networking opportunities for developers and business leaders looking to explore or advance their generative AI journey. These events are hosted across multiple global locations including San Francisco, Berlin, Dubai, Dublin, Bengaluru, Manchester, Paris, and Tel Aviv, providing accessible opportunities to accelerate your generative AI adoption.

And that’s it for this week! Come back next Monday for more highlights and keep your AWS knowledge up to date as we cover the latest releases.

Matheus Guimaraes | @codingmatheus

New Amazon EC2 P6e-GB200 UltraServers accelerated by NVIDIA Grace Blackwell GPUs for the highest AI performance

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6e-gb200-ultraservers-powered-by-nvidia-grace-blackwell-gpus-for-the-highest-ai-performance/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6e-GB200 UltraServers, accelerated by NVIDIA GB200 NVL72 to offer the highest GPU performance for AI training and inference. Amazon EC2 UltraServers connect multiple EC2 instances using a dedicated, high-bandwidth, and low-latency accelerator interconnect across these instances.

The NVIDIA Grace Blackwell Superchips connect two high-performance NVIDIA Blackwell tensor core GPUs and an NVIDIA Grace CPU based on Arm architecture using the NVIDIA NVLink-C2C interconnect. Each Grace Blackwell Superchip delivers 10 petaflops of FP8 compute (without sparsity) and up to 372 GB HBM3e memory. With the superchip architecture, GPU and CPU are colocated within one compute module, increasing bandwidth between GPU and CPU significantly compared to current generation EC2 P5en instances.

With EC2 P6e-GB200 UltraServers, you can access up to 72 NVIDIA Blackwell GPUs within one NVLink domain to use 360 petaflops of FP8 compute (without sparsity) and 13.4 TB of total high bandwidth memory (HBM3e). Powered by the AWS Nitro System, P6e-GB200 UltraServers are deployed in EC2 UltraClusters to securely and reliably scale to tens of thousands of GPUs.

EC2 P6e-GB200 UltraServers deliver up to 28.8 Tbps of total Elastic Fabric Adapter (EFAv4) networking. EFA is also coupled with NVIDIA GPUDirect RDMA to enable low-latency GPU-to-GPU communication between servers with operating system bypass.

EC2 P6e-GB200 UltraServers specifications
EC2 P6e-GB200 UltraServers are available in sizes ranging from 36 to 72 GPUs under NVLink. Here are the specs for EC2 P6e-GB200 UltraServers:

UltraServer type GPUs
GPU
memory (GB)
vCPUs Instance memory
(GiB)
Instance storage (TB) Aggregate EFA Network Bandwidth (Gbps) EBS bandwidth (Gbps)
u-p6e-gb200x36 36 6660 1296 8640 202.5 14400 540
u-p6e-gb200x72 72 13320 2592 17280 405 28800 1080

P6e-GB200 UltraServers are ideal for the most compute and memory intensive AI workloads, such as training and inference of frontier models, including mixture of experts models and reasoning models, at the trillion-parameter scale.

You can build agentic and generative AI applications, including question answering, code generation, video and image generation, speech recognition, and more.

P6e-GB200 UltraServers in action
You can use EC2 P6e-GB200 UltraServers in the Dallas Local Zone through EC2 Capacity Blocks for ML. The Dallas Local Zone (us-east-1-dfw-2a) is an extension of the US East (N. Virginia) Region.

To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console. You can select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for u-p6e-gb200x36 or u-p6e-gb200x72 UltraServers.

Once Capacity Block is successfully scheduled, it is charged up front and its price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

To run instances within your purchased Capacity Block, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs. On the software side, you can start with the AWS Deep Learning AMIs. These images are preconfigured with the frameworks and tools that you probably already know and use: PyTorch, JAX, and a lot more.

You can also integrate EC2 P6e-GB200 UltraServers seamlessly with various AWS managed services. For example:

  • Amazon SageMaker Hyperpod provides managed, resilient infrastructure that automatically handles the provisioning and management of P6e-GB200 UltraServers, replacing faulty instances with preconfigured spare capacity within the same NVLink domain to maintain performance.
  • Amazon Elastic Kubernetes Services (Amazon EKS) allows one managed node group to span across multiple P6e-GB200 UltraServers as nodes, automating their provisioning and lifecycle management within Kubernetes clusters. You can use EKS topology-aware routing for P6e-GB200 UltraServers, enabling optimal placement of tightly coupled components of distributed workloads within a single UltraServer’s NVLink-connected instances.
  • Amazon FSx for Lustre file systems provide data access for P6e-GB200 UltraServers at the hundreds of GB/s of throughput and millions of input/output operations per second (IOPS) required for large-scale HPC and AI workloads. For fast access to large datasets, you can use up to 405 TB of local NVMe SSD storage or virtually unlimited cost-effective storage with Amazon Simple Storage Service (Amazon S3).

Now available
Amazon EC2 P6e-GB200 UltraServers are available today in the Dallas Local Zone (us-east-1-dfw-2a) through EC2 Capacity Blocks for ML. For more information, visit the Amazon EC2 pricing page.

Give Amazon EC2 P6e-GB200 UltraServers a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 P6e instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Introducing AWS Builder Center: A new home for the AWS builder community

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-aws-builder-center-a-new-home-for-the-aws-builder-community/

We really love builders at AWS. We’re constantly thinking of new ways to help technical communities thrive and create spaces like AWS Developer Center and community.aws where people can connect and share their knowledge and experiences.

Today, we’re announcing AWS Builder Center, a new home for builders to access all builder resources, engage with the AWS community, and provide feedback or product suggestions to AWS product teams. This new experience also integrates the previous AWS Developer Center and community.aws.

There are a variety of exciting features so let us discover some of them.

Your voice matters: Introducing Wishlist
One of the most exciting new features, in my opinion, is Wishlist. You can now submit your wishes for new features or improvements you’d like to see in AWS services. Others can discover and vote on these wishes while also creating their own.

You can influence product roadmap collectively as a community and help us shape the future of AWS services. You can share ideas, suggestions, feature proposals, or challenges while operating AWS services, with the ability for the AWS community to upvote ideas and highlight the most sought-after improvements. Our internal teams will keep an eye on these and bring the most popular wishes to the attention of our service teams, making your voice an integral part of our product development process.

Connect people in the AWS community
On the Connect page, you’ll find many opportunities to connect directly with AWS Heroes and AWS Community Builders. You can explore and join AWS User Groups and AWS Cloud Clubs near your cities around the world.

On top of that, you can bookmark this page as your centralized hub for finding upcoming community events, making it easy to find opportunities to learn and network in your local area and meet like-minded builders who share your interests.

Speaking of following people, AWS Builder Center makes it really straightforward to connect and engage with others, serving as the central hub for the AWS technical community. It brings together all the different ways that you can connect with fellow builders. For example, the Who to Follow section introduces you to AWS Heroes, Community Builders, and active community members who are sharing their knowledge and expertise in your areas of interest.

Explore our AWS hands-on resources
On the Build page, you’ll discover ways to get familiar with AWS with hands-on experience such as interactive learning resources designed for every skill level such as AWS Tutorials and AWS Workshops. You can explore generative AI and agentic AI services playground and find the AWS Free Tier to try out AWS services free of charge up to specified limits for each service.

Choose the Toolbox page and discover the latest tools, programming language resources, and Open Source projects for AWS. The Toolbox has everything you need to get your project scaffolded and up and running.

To improve the build experience for builders, we plan to expand Builder Center’s built-in offerings such as creating dedicated groups and forums for collaborating on a particular topic, run workshops for hands-on labs, and various service playgrounds where builders can freely experiment with AWS services.

Supporting your builder journey
The new Learn section serves as your gateway to skill development, bringing together everything you need to expand your AWS expertise. Here, you can explore learning and training resources, workshops, gamified experiences, and more to make your journey of building on AWS both educational and engaging.

Choose the Topics page, where you can explore and discover more content. You can explore content by topics and tags. There is a featured and trending topics section that helps you to stay connected with what’s capturing the community’s attention right now.

Built-in localization for your spoken language
AWS Builder Center breaks down language barriers with comprehensive localization support. All content published in the Builder Center is automatically available in 16 languages, and user-generated content, such as posts, comments, or wishes, can be machine-translated on demand using Translate. So, you can collaborate with builders worldwide, sharing knowledge and experiences across language boundaries.

By default, all content will be displayed in based on the language that your browser is set to. But, you can override this by visiting the settings page and choosing the language that you want AWS Builder Center to use by default.

Sign up and build your profile now
AWS Builder Center gives you a more personalized and comprehensive way to showcase your AWS journey. Your unique profile comes with a custom URL and shareable QR code, making it straightforward to connect with others and share your presence in the AWS community.

All your posts, wishes, and meaningful interactions are organized within a centralized view so you can easily check them. In the Manage profile page, you can customize your profile, add specific interests and areas of expertise, helping you connect with builders who share your passions. Profile management is seamless: it synchronizes across all AWS services using AWS Builder ID, ensuring your identity remains consistent wherever you engage with AWS offerings.

Visit builder.aws.com, sign up with AWS Builder ID, and claim your unique alias to access all features, including content creation, Wishlist, and community engagement tools.

AWS Builder Center was designed to help you connect, learn, and build with fellow AWS builders, so enjoy your journey together!

— Channy & Matheus Guimaraes | @codingmatheus

Introducing Oracle Database@AWS for simplified Oracle Exadata migrations to the AWS Cloud

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-oracle-databaseaws-for-simplified-oracle-exadata-migrations-to-the-aws-cloud/

Today, we’re announcing the general availability of Oracle Database@AWS, a new offering for Oracle Exadata workloads, including Oracle Real Application Clusters (RAC) within AWS.

In the past 14 years, customers had the choice of self-managing Oracle database workloads in the cloud using Amazon Elastic Compute Cloud (Amazon EC2) or using fully managed Amazon Relational Database Service (Amazon RDS) for Oracle. Now, you have an additional option for your workloads that require Oracle RAC or Oracle Exadata for quicker and simpler migrations to the cloud. You also get a single invoice through AWS Marketplace, which counts towards AWS commitments and Oracle license benefits, including Bring Your Own License (BYOL) and discount programs such as Oracle Support Rewards.

With Oracle Database@AWS, you can migrate your Oracle Exadata workloads to Oracle Exadata Database Service on Dedicated Infrastructure or Oracle Autonomous Database on Dedicated Exadata Infrastructure within AWS with minimal changes. You can purchase, provision, and manage your Oracle Database@AWS deployments through familiar AWS tools and interfaces such as AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS APIs for applications running on AWS. The AWS APIs call the corresponding Oracle Cloud Infrastructure (OCI) APIs necessary to provision and manage the resources.

Since its preview last December, we’ve improved or added features to help run production workloads at general availability:

  • Regional expansion – You can now use Oracle Database@AWS in the U.S. East (N. Virginia) and U.S. West (Oregon) Regions today. We are also announcing plans to expand to 20 AWS Regions globally. This broader availability supports the diverse needs of our customers across various geographical areas so more enterprises can benefit from this option. You can choose from different Exadata system sizes to match your workload requirements in your AWS Region.
  • Zero-ETL and S3 backups – You can now benefit from zero-ETL integration with Amazon Redshift for analytics to remove the need to build and manage data pipelines for extract, transform, and load operations. With zero-ETL, you can unify your data on AWS without incurring cross network data transfer costs. We’re providing Amazon Simple Storage Service (Amazon S3) backups with up to eleven nines of data durability.
  • Autonomous VM cluster – You can now provision an Autonomous VM Cluster in addition to an Exadata VM cluster on the Exadata Dedicated Infrastructure. You can run Oracle Autonomous Database on Dedicated Exadata Infrastructure, a fully managed database environment using committed hardware and software resources.

Oracle Database@AWS also integrates with other AWS services such as Amazon Virtual Private Cloud (Amazon VPC) Lattice for configuring network paths to AWS services such as S3 and Redshift directly, AWS Identity and Access Management (IAM) for authentication and authorization, Amazon EventBridge for monitoring database lifecycle events, AWS CloudFormation for infrastructure automation, Amazon CloudWatch for collecting and monitoring metrics, and AWS CloudTrail for logging API operations.

Getting started with Oracle Database@AWS
Oracle Database@AWS supports two key services: Oracle Exadata Database Service on Dedicated Infrastructure and Oracle Autonomous Database on Dedicated Exadata Infrastructure within AWS data centers.

These services physically reside within an Availability Zone in an AWS Region and logically reside in an OCI region, enabling seamless integration with AWS services through high-speed, low-latency connections.

You create an ODB network, a private, isolated network that hosts Oracle Exadata VM Clusters within an Availability Zone. Then, you use ODB peering accessible to EC2 application servers running in a VPC. To learn more, visit How Oracle Database@AWS works in the AWS documentation.

Request a private offer in AWS Marketplace

To begin your journey with Oracle Database@AWS, visit the AWS console or request the AWS Marketplace private offer. Your AWS and Oracle sales team will receive your request, then contact you to find the best option for your workloads, and activate your account.

When you activate and get access to Oracle Database@AWS, you can use the Dashboard to create an ODB network, Exadata infrastructure, and Exadata VM cluster or Autonomous VM cluster, and ODB peering connection.

To learn more, visit the Onboarding to Oracle Database@AWS and AWS Marketplace buyer private offers in the AWS documentation.

Create an ODB network

An ODB network is a private isolated network that hosts OCI infrastructure on AWS. The ODB network maps directly to the network that exists within the OCI child site, thus serving as the means of communication between AWS and OCI.

In the Dashboard, choose Create ODB network, enter a network name, choose the Availability Zone, and specify a CIDR ranges for client connections established by applications and backup connections used for taking automated backups. You can also enter a name to use as a prefix to your domain fixed as oraclevcn.com. For example, if you enter myhost, the fully qualified domain name is myhost.oraclevcn.com.

Optionally, you can configure ODB network access to perform automated backups to Amazon S3 and zero-ETL for near real-time analytics and ML on your Oracle data using Amazon Redshift.

After you create your ODB network, update your VPC route tables of your EC2 application servers with the client connection CIDR in the ODB network. To learn more, visit ODB network, ODB peering, and Configuring VPC route tables for ODB peering in the AWS documentation.

Create Exadata infrastructure

The Oracle Exadata infrastructure is the underlying architecture of your database servers, storage servers, and networking that run your Oracle Exadata databases.

Choose Create Exadata infrastructure, enter a name, and use the default Availability Zone. In the next step, you can choose Exadata.X11M for the Exadata system model. You can also set a default of 2 or up to 32 database servers and 3 or up to 64 storage servers with 80 TB storage capacity per server.

Finally, you can configure system maintenance preferences, such as scheduling, patching mode, and OCI maintenance notification contacts. You can’t modify an infrastructure after you create it from the AWS console. But, you can navigate to the OCI console and modify it.

To delete an Exadata infrastructure, visit Deleting an Oracle Exadata infrastructure in Oracle Database@AWS in the AWS documentation.

Create an Exadata VM cluster or Autonomous VM cluster

You can create VM clusters on Exadata infrastructure and deploy multiple VM clusters with different Oracle Exadata infrastructures in the same ODB network.

Here are two types of VM clusters:

  • An Exadata VM cluster is a set of virtual machines that has a complete Oracle database installation that includes all features of Oracle Enterprise Edition.
  • An Autonomous VM cluster is a set of fully managed databases that automate key management tasks using AI/ML with no human intervention required.

Choose Create Exadata VM cluster, enter a VM cluster name and a time zone, choose Bring Your Own License (BYOL) or license included for license options. In the next step, you can choose your Exadata infrastructure, grid infrastructure version, and Exadata image version. For database servers, you can choose the CPU core count, memory, and local storage for each VM or accept the defaults.

In the next step, you can configure the connectivity setting by choosing your ODB network and entering a prefix for the VM cluster. You can enter a port number for TCP access to the single client access name (SCAN) listener. The default port is 1521 or you can enter a custom SCAN port in the range 1024–8999. For SSH key pairs, enter the public key portion of one or more key pairs used for SSH access to the VM cluster.

Then, you can choose diagnostics and tags, review your settings, and create a VM cluster. The creation process can take up to 6 hours, depending on the size of the VM cluster.

Create and manage an Oracle database

When the VM cluster is ready, you can create and manage your Oracle Exadata databases in the OCI console. Choose Manage in OCI in the details page of the Exadata VM cluster. You will be redirected to the OCI console.

When you create an Oracle Database in the OCI console, you can select Oracle Database 19c or 23ai. When enabling automatic backups for your provisioned databases, you can use an S3 bucket or OCI Object Storage in the OCI region. To learn more, visit Provision Oracle Exadata Database Service in Oracle Database@AWS in the OCI documentation.

Things to know
Here are a couple of things to know about Oracle Database@AWS:

  • Monitoring – You can monitor Oracle Database@AWS using Amazon CloudWatch metrics in the AWS/ODB namespaces for VM clusters, container databases, and pluggable databases. AWS CloudTrail captures all AWS API calls for Oracle Database@AWS as events. Using CloudTrail logs, you can determine the request that was made to Oracle Database@AWS, the IP address from which the request was made, when it was made, and additional details. To learn more, visit Monitoring Oracle Database@AWS.
  • Security – You can use IAM to assign permissions that determine who is allowed to manage Oracle Database@AWS resources and SSL/TLS encrypted connections to secure data. You can also use Amazon EventBridge for seamless event-driven database operations—all working together to maintain security standards while enabling efficient cloud operations. To learn more, visit Security in Oracle Database@AWS.
  • Compliance – Your compliance responsibility when using Oracle Database@AWS is determined by the sensitivity of your data, your company’s compliance objectives, and applicable laws and regulations. We provides the following compliances with Oracle Database@AWS: SOC 1, SOC 2, SOC 3, HIPAA, C5, CSA STAR Attest, CSA STAR Cert, HDS (France), ISO Series (ISO/IEC 9001, 20000-1, 27001, 27017, 27018, 27701, 22301), PCI DSS, and HITRUST. To learn more, visit Compliance validation for Oracle Database@AWS.
  • Support – Your AWS or Oracle sales account team can help you evaluate your current database infrastructure, determine how Oracle Database@AWS can best serve your organization’s requirements, and develop a tailored migration strategy and timeline. You can also get help from AWS Oracle Competency Partners specialized to architect, deploy, and manage Oracle-based workloads running in the AWS Cloud.

Now available and coming soon
Oracle Database@AWS is now available in the U.S. East (N. Virginia) and U.S. West (Oregon) Regions through the AWS Marketplace. Oracle Database@AWS pricing and any AWS Marketplace private offers are set by Oracle. You can see specific details around pricing on Oracle’s pricing page for the offering.

Oracle Database@AWS will expand to 20 more AWS Regions across the Americas, Europe, and Asia-Pacific including: US East (Ohio), US West (N. California), Asia Pacific (Hyderabad), Asia Pacific (Melbourne), Asia Pacific (Mumbai), Asia Pacific (Osaka), Asia Pacific (Seoul), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Canada (Central), Europe (Frankfurt), Europe (Ireland), Europe (London), Europe (Milan), Europe (Paris), Europe (Spain), Europe (Stockholm), Europe (Zurich), and South America (São Paulo).

You can get started with Oracle Database@AWS with using AWS console. To learn more, visit the Oracle Database@AWS User Guide and OCI documentation and send feedback through your usual AWS Support contacts or OCI support.

— Channy

AWS Weekly Roundup: EC2 C8gn instances, Amazon Nova Canvas virtual try-on, and more (July 7, 2025)

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-bedrock-api-keys-amazon-nova-canvas-virtual-try-on-and-more-july-7-2025/

Every Monday we tell you about the best releases and blogs that caught our attention last week.

Before continuing with this AWS Weekly Roundup, I’d like to share that last month I moved with my family to San Francisco, California, to start a new role as Developer Advocate/SDE, GenAI.

This excites me because I’ll have the opportunity to connect with new communities in the Bay Area while tackling exciting new challenges. If you’re part of a community focused on building generative AI and agentics applications, or know of one, I’d love to connect. Let’s connect!

Last week’s launches
Here are the launches from last week:

  • New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth – Amazon Elastic Compute Cloud (Amazon EC2) C8gn instances are now generally available, powered by AWS Graviton4 processors and 6th generation AWS Nitro Cards. These network-optimized instances deliver up to 600 Gbps network bandwidth. This represents the highest bandwidth among EC2 network-optimized instances, with up to 192 vCPUs and 384 GiB memory. They provide 30% higher compute performance than C7gn instances and are ideal for network-intensive workloads like virtual appliances, data analytics, and cluster computing jobs.
  • Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables – Amazon DynamoDB global tables now supports multi-Region strong consistency (MRSC) for applications requiring zero Recovery Point Objective (RPO). This capability ensures applications can read the latest data from any Region during outages, addressing critical needs in payment processing and financial services. MRSC requires three AWS Regions configured as either three full replicas or two replicas plus a witness, providing the highest level of application resilience for mission-critical workloads.
  • Amazon Nova Canvas update: Virtual try-on and style options now available – Amazon Nova Canvas introduces virtual try-on capabilities that help you visualize how clothing looks on a person by combining two images, plus eight new pre-trained style options (3D animation, design sketch, vector illustration, graphic novel, etc.) for generating images with improved artistic consistency. Available in three AWS Regions, these features enhance AI-powered image generation capabilities for retailers and content creators seeking realistic product visualizations.
  • Amazon Q in Connect now supports 7 languages for proactive recommendations – Amazon Q in Connect, a generative AI-powered assistant for customer service, now provides proactive recommendations in seven languages: English, Spanish, French, Portuguese, Mandarin, Japanese, and Korean. The AI-powered customer service assistant detects customer intent during voice and chat interactions to help agents resolve issues quickly and accurately.
  • Amazon Aurora MySQL and Amazon RDS for MySQL integration with Amazon SageMaker is now available – This integration provides near real-time data availability for analytics. It automatically extracts MySQL data into lakehouses with Apache Iceberg compatibility. You can then access this data seamlessly through various analytics engines and machine learning tools.
  • Amazon Aurora DSQL is now available in additional AWS Regions – Amazon Aurora DSQL expands to Asia Pacific (Seoul) and now supports multi-Region clusters across Asia Pacific and European regions. This serverless, distributed SQL database offers unlimited scalability, highest availability, and zero infrastructure management with AWS Free Tier access.

Other AWS blog posts

  • Optimize RAG in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service – Learn how to optimize Retrieval Augmented Generation (RAG) in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service. This comprehensive guide demonstrates implementing RAG workflows with LangChain, covers OpenSearch optimization strategies, provides setup instructions, and explains benefits of combining these AWS services for scalable, cost-effective generative AI applications.v
  • Agentic GenAI App Using Bedrock, MCP servers on EKS – This post shows how to build a scalable AI chat application using Amazon Bedrock, Strands Agent, and Model Context Protocol (MCP) servers deployed on Amazon Elastic Kubernetes Service (Amazon EKS). The architecture combines agentic workflows with containerized microservices for intelligent, auto-scaling conversations with multiple foundation models.
  • Enforce table level access control on data lake tables using AWS Glue 5.0 with AWS Lake Formation – AWS Glue 5.0 introduces Full-Table Access (FTA) control for Apache Spark with AWS Lake Formation, providing table-level security without fine-grained access overhead. This feature supports native Spark SQL/DataFrames for Lake Formation tables. It enables read/write operations on Iceberg and Hive tables with improved performance and lower costs.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. Early-career professionals can apply for the All Builders Welcome Grant program, designed to remove financial barriers and create diverse pathways into cloud technology. Applications are now open and close on July 15, 2025.
  • AWS NY Summit – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
  • Join AWS Gen AI Lofts – Experience AWS Gen AI Lofts across San Francisco, Berlin, Dubai, Dublin, Bengaluru, Manchester, Paris, Tel Aviv, and additional locations – hands-on workshops, expert guidance, investor networking, and collaborative spaces designed to accelerate your generative AI startup journey.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Eli

Amazon Nova Canvas update: Virtual try-on and style options now available

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/amazon-nova-canvas-update-virtual-try-on-and-style-options-now-available/

Have you ever wished you could quickly visualize how a new outfit might look on you before making a purchase? Or how a piece of furniture would look in your living room? Today, we’re excited to introduce a new virtual try-on capability in Amazon Nova Canvas that makes this possible. In addition, we are adding eight new style options for improved style consistency for text-to-image based style prompting. These features expand Nova Canvas AI-powered image generation capabilities making it easier than ever to create realistic product visualizations and stylized images that can enhance the experience of your customers.

Let’s take a quick look at how you can start using these today.

Getting started
The first thing is to make sure that you have access to the Nova Canvas model through the usual means. Head to the Amazon Bedrock console, choose Model access and enable Amazon Nova Canvas for your account making sure that you select the appropriate regions for your workloads. If you already have access and have been using Nova Canvas, you can start using the new features immediately as they’re automatically available to you.

Virtual try-on
The first exciting new feature is virtual try-on. With this, you can upload two pictures and ask Amazon Nova Canvas to put them together with realistic results. These could be pictures of apparel, accessories, home furnishings, and any other products including clothing. For example, you can provide the picture of a human as the source image and the picture of a garment as the reference image, and Amazon Nova Canvas will create a new image with that same person wearing the garment. Let’s try this out!

My starting point is to select two images. I picked one of myself in a pose that I think would work well for a clothes swap and a picture of an AWS-branded hoodie.

Matheus and AWS-branded hoodie

Note that Nova Canvas accepts images containing a maximum of 4.1M pixels – the equivalent of 2,048 x 2,048 – so be sure to scale your images to fit these constraints if necessary. Also, if you’d like to run the Python code featured in this article, ensure you have Python 3.9 or later installed as well as the Python packages boto3 and pillow.

To apply the hoodie to my photo, I use the Amazon Bedrock Runtime invoke API. You can find full details on the request and response structures for this API in the Amazon Nova User Guide. The code is straightforward, requiring only a few inference parameters. I use the new taskType of "VIRTUAL_TRY_ON". I then specify the desired settings, including both the source image and reference image, using the virtualTryOnParams object to set a few required parameters. Note that both images must be converted to Base64 strings.

import base64


def load_image_as_base64(image_path): 
   """Helper function for preparing image data."""
   with open(image_path, "rb") as image_file:
      return base64.b64encode(image_file.read()).decode("utf-8")


inference_params = {
   "taskType": "VIRTUAL_TRY_ON",
   "virtualTryOnParams": {
      "sourceImage": load_image_as_base64("person.png"),
      "referenceImage": load_image_as_base64("aws-hoodie.jpg"),
      "maskType": "GARMENT",
      "garmentBasedMask": {"garmentClass": "UPPER_BODY"}
   }
}

Nova Canvas uses masking to manipulate images. This is a technique that allows AI image generation to focus on specific areas or regions of an image while preserving others, similar to using painter’s tape to protect areas you don’t want to paint.

You can use three different masking modes, which you can choose by setting maskType to the correct value. In this case, I’m using "GARMENT", which requires me to specify which part of the body I want to be masked. I’m using "UPPER_BODY" , but you can use others such as "LOWER_BODY", "FULL_BODY", or "FOOTWEAR" if you want to specifically target the feet. Refer to the documentation for a full list of options.

I then call the invoke API, passing in these inference arguments and saving the generated image to disk.

# Note: The inference_params variable from above is referenced below.

import base64
import io
import json

import boto3
from PIL import Image

# Create the Bedrock Runtime client.
bedrock = boto3.client(service_name="bedrock-runtime", region_name="us-east-1")

# Prepare the invocation payload.
body_json = json.dumps(inference_params, indent=2)

# Invoke Nova Canvas.
response = bedrock.invoke_model(
   body=body_json,
   modelId="amazon.nova-canvas-v1:0",
   accept="application/json",
   contentType="application/json"
)

# Extract the images from the response.
response_body_json = json.loads(response.get("body").read())
images = response_body_json.get("images", [])

# Check for errors.
if response_body_json.get("error"):
   print(response_body_json.get("error"))

# Decode each image from Base64 and save as a PNG file.
for index, image_base64 in enumerate(images):
   image_bytes = base64.b64decode(image_base64)
   image_buffer = io.BytesIO(image_bytes)
   image = Image.open(image_buffer)
   image.save(f"image_{index}.png")

I get a very exciting result!

Matheus wearing AWS-branded hoodie

And just like that, I’m the proud wearer of an AWS-branded hoodie!

In addition to the "GARMENT" mask type, you can also use the "PROMPT" or "IMAGE" masks. With "PROMPT", you also provide the source and reference images, however, you provide a natural language prompt to specify which part of the source image you’d like to be replaced. This is similar to how the "INPAINTING" and "OUTPAINTING" tasks work in Nova Canvas. If you want to use your own image mask, then you choose the "IMAGE" mask type and provide a black-and-white image to be used as mask, where black indicates the pixels that you want to be replaced on the source image, and white the ones you want to preserve.

This capability is specifically useful for retailers. They can use it to help their customers make better purchasing decisions by seeing how products look before buying.

Using style options
I’ve always wondered what I would look like as an anime superhero. Previously, I could use Nova Canvas to manipulate an image of myself, but I would have to rely on my good prompt engineering skills to get it right. Now, Nova Canvas comes with pre-trained styles that you can apply to your images to get high-quality results that follow the artistic style of your choice. There are eight available styles including 3D animated family film, design sketch, flat vector illustration, graphic novel, maximalism, midcentury retro, photorealism, and soft digital painting.

Applying them is as straightforward as passing in an extra parameter to the Nova Canvas API. Let’s try an example.

I want to generate an image of an AWS superhero using the 3D animated family film style. To do this, I specify a taskType of "TEXT_IMAGE" and a textToImageParams object containing two parameters: text and style. The text parameter contains the prompt describing the image I want to create which in this case is “a superhero in a yellow outfit with a big AWS logo and a cape.” The style parameter specifies one of the predefined style values. I’m using "3D_ANIMATED_FAMILY_FILM" here, but you can find the full list in the Nova Canvas User Guide.

inference_params = {
   "taskType": "TEXT_IMAGE",
   "textToImageParams": {
      "text": "a superhero in a yellow outfit with a big AWS logo and a cape.",
      "style": "3D_ANIMATED_FAMILY_FILM",
   },
   "imageGenerationConfig": {
      "width": 1280,
      "height": 720,
      "seed": 321
   }
}

Then, I call the invoke API just as I did in the previous example. (The code has been omitted here for brevity.) And the result? Well, I’ll let you judge for yourself, but I have to say I’m quite pleased with the AWS superhero wearing my favorite color following the 3D animated family film style exactly as I envisioned.

What’s really cool is that I can keep my code and prompt exactly the same and only change the value of the style attribute to generate an image in a completely different style. Let’s try this out. I set style to PHOTOREALISM.

inference_params = { 
   "taskType": "TEXT_IMAGE", 
   "textToImageParams": { 
      "text": "a superhero in a yellow outfit with a big AWS logo and a cape.",
      "style": "PHOTOREALISM",
   },
   "imageGenerationConfig": {
      "width": 1280,
      "height": 720,
      "seed": 7
   }
}

And the result is impressive! A photorealistic superhero exactly as I described, which is a far departure from the previous generated cartoon and all it took was changing one line of code.

Things to know
Availability – Virtual try-on and style options are available in Amazon Nova Canvas in the US East (N. Virginia), Asia Pacific (Tokyo), and Europe (Ireland). Current users of Amazon Nova Canvas can immediately use these capabilities without migrating to a new model.

Pricing – See the Amazon Bedrock pricing page for details on costs.

For a preview of virtual try-on of garments, you can visit nova.amazon.com where you can upload an image of a person and a garment to visualize different clothing combinations.

If you are ready to get started, please check out the Nova Canvas User Guide or visit the AWS Console.

Matheus Guimaraes | @codingmatheus

What’s new in Zabbix 7.4

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/whats-new-in-zabbix-7-4/30597/

With the release of Zabbix 7.4, Zabbix users will be able to further extend their existing resource discovery workflows and enjoy a wastly improved user experience when it comes to configuring Zabbix entities. In addition, the latest release introduces multiple dashboard and network map improvements which will further enhance the visualization of infrastructure and resources.

Host Wizard

Host creation can be somewhat confusing for Zabbix beginners. Creating a host and applying a template involves numerous steps – from creating a host and assigning it to a host group, to configuring appropriate host interfaces, applying a template, and editing template-level macros to adjust the default problem thresholds and filters.

The Host Wizard aims to simplify the host onboarding process by providing a step-by-step guide for creating and configuring a host.

The Host Wizard can be opened from the Data Collection – Hosts section

A new Host Wizard button has been added to the Data Collection – Hosts section. Once you click on it, you will first have to select the template you wish to apply on the new host. Only one template can be applied at a time, so if you wish to apply multiple templates on a single host via Host Wizard, you will have to do so via one template and one Host Wizard session at a time.

Under the hood, if we look at the template files, the templates have also received 2 new parameters: wizard_ready and readme. Only templates marked with wizard_ready: ‘YES’ can be selected in the Host Wizard.

Filter for and select the required template

After you have selected the template, you will be prompted to enter a host name and select host groups. You can create a new host or apply the template on an existing host.

Provide a host name and select host groups

The next steps include the deployment instructions. Depending on the selected template type, the Host Wizard will provide all of the required instructions to start monitoring the host with the chosen template.

The Host Wizard will provide the required host configuration steps

In the final Host Wizard steps, you will be prompted to add the required host interface, read the template notes, and customize the template-level macros.

Customize template-level macros to modify the default filters, problem thresholds, and other parameters

Nested low-level discovery rules and host prototypes

Low-level discovery rules have received major improvements in Zabbix 7.4. It is now possible to create nested low-level discovery rules, while host prototypes are now capable of discovering hosts of their own with low-level discovery.

A new type of prototype has been added to low-level discovery rules – discovery prototype. These prototypes are used together with low-level discovery macros to automatically create low-level discovery rules for resource discovery.

Discovery prototypes can now be created in low-level discovery rules

A new item type has been added for discovery rule prototypes – Nested. This type of discovery rule iterates through the JSON file received by the parent low-level discovery rule to discover child entities. For example:

[   {     "database": "db1",     "created_at": "2024-02-01T12:30:00Z",     "encoding": "UTF8",     "tablespaces": [       { "name": "ts1", "max_size": "10GB" },       { "name": "ts2", "max_size": "20GB" },       { "name": "ts3", "max_size": "15GB" }     ]   },   {     "database": "db2",     "created_at": "2023-11-15T08:45:00Z",     "encoding": "UTF16",     "tablespaces": [       { "name": "ts1", "max_size": "5GB" },       { "name": "ts2", "max_size": "25GB" },       { "name": "ts3", "max_size": "30GB" }     ]   },   {     "database": "db3",     "created_at": "2024-01-05T15:10:00Z",     "encoding": "UTF8",     "tablespaces": [       { "name": "ts1", "max_size": "12GB" },       { "name": "ts2", "max_size": "18GB" },       { "name": "ts3", "max_size": "22GB" }     ]   } ]

If we set the jsonpath preprocessing in the discovery rule prototype to JSONPath=$.tablespaces and set the low-level discovery macro to {#TSNAME}=$.name, the nested low-level discovery rule will create discovery rules to discover tablespaces for each database.

Low-level discovery rules are created from the discovery prototype

Inline form validation

Inline validation has been introduced with the goal of improving the overall user experience when configuring a variety of Zabbix entities. As of Zabbix 7.4, inline form validation is supported in:

  • Host configuration
  • Template configuration
  • Item configuration
  • Trigger configuration
Inline validation detects any configuration errors on the fly and displays a corresponding error message

With inline validation in place, users will now receive immediate feedback regarding any configuration mistakes they have made in the sections above. Configuring new entities, especially items and triggers with complex keys and expressions, is now faster than ever.

Frontend-to-server communication encryption

To further strengthen Zabbix communication flow security, Zabbix 7.4 introduces the ability to secure frontend to server communication with certificate encryption. The encryption must be configured from two sides, and the frontend setup now includes the options to enable and configure encrypted connections to the server.


Zabbix 7.4 introduces the ability to encrypt frontend-to-server connections

On the Zabbix server side, multiple new configuration parameters have been added:

  • TLSFrontendAccept – which incoming connections to accept from frontend
  • TLSFrontendCertIssuer – allowed frontend certificate issuer
  • TLSFrontendCertSubject – allowed frontend certificate subject
  • FrontendAllowedIP – frontend connections will be accepted only from addresses listed here if the parameter is set

New widgets and visualization improvements

Zabbix 7.4 introduces a new widget (Item card) and multiple visualization improvements for dashboards and network maps.

Item card widget

The new Item card widget behaves similarly to the existing Host card widget introduced in Zabbix 7.2. The Item card widget provides a customizable view of an item and its attributes, such as latest data together with a sparkling chart, error messages, interfaces, tags, triggers, and more. The attributes for display can be selected and ordered in the widget configuration.

Various item attributes can be displayed in the item card widget

Network map improvements

Network maps have also received multiple improvements, enabling new use cases and simplifying existing network map scenarios.

  • Map background images can now be scaled proportionally to the map dimensions
  • Map links now support link indicators based on item value thresholds
  • Map element icons can now be ordered when placed on top of one another
Item value thresholds can be defined for link indicators
  • Map element icons can now be ordered when placed on top of one another
  • Host group map elements will now take into account nested host groups when displaying host group-related information
  • Map link and element labels can now be hidden and only displayed on mouse hover
Map elements can be ordered on top of each other

Dashboard improvements

Zabbix 7.4 introduces multiple dashboard improvements to facilitate faster and smoother dashboard configuration.

The color picker in graph and pie chart widgets has been extended with the new palette color scheme in addition to the existing solid color scheme. Users can choose from the available palette color schemes. The new palette color schemes display the values within a data set in a more distinguishable way, while the existing solid color scheme displays the data set values in shades of the selected color.

The new palette color scheme is available in graph and pie chart widgets

Widget configuration changes are also displayed instantly in Zabbix 7.4 – there’s  no need anymore to apply the changes to see them reflected in the widget.

In addition, the default Global view dashboard has received an overhaul and now utilizes the latest Zabbix widgets to provide additional insights about the Zabbix instance.

The default Global view dashboard has received an overhaul

Other changes in Zabbix 7.4

Multiple smaller fixes have been introduced in Zabbix 7.4, such as new history functions, new macros, security fixes, and more:

  • Preprocessing results can now be copied directly to clipboard by using the “Copy to clipboard” button
  • All users are now allowed to manage their own media by default. These permissions can now be revoked in user role settings
  • A new Notifications section for customizing notification settings has been added under “User Settings”
  • Vault secret macros can now be resolved by either the Zabbix server or Zabbix proxy
  • A new icmppingretry simple check has been added to monitor host responses to ICMP ping with the ability to modify retries
  • New timestamp tracking history functions have been added
  • Multiple new macros added for item-value time tracking
  • Zabbix server/proxy automatically logs history cache diagnostic information when the history cache is full
  • Disabled items are now immediately removed from the history cache
  • It is now possible to manually clear the history cache for a specific item by its id with the history_cache_clear=target runtime command
  • Added support of Gmail OAuth authentication

New templates and integrations in Zabbix 7.4

Many of the existing webhook integrations have been refactored in Zabbix 7.4. The webhooks have been optimized for the best possible performance and include a variety of fixes:

  • Discord
  • GitHub
  • GLPi
  • Jira
  • Jira Service management
  • MS Teams
  • MS Teams Workflows
  • OTRS CE
  • PagerDuty
  • Slack
  • Telegram
  • Zammad
Many of the existing webhook integrations have been refactored in Zabbix 7.4

Multiple new templates have also been introduced:

  • Pure Storage FlashArray
  • Azure SQL Managed Instance
  • Azure MSSQL DTU database by HTTP
  • Azure Backup Jobs by HTTP
  • Palo Alto PA-440
  • Juniper MX
  • Improvements for Dell by HTTP and SNMP templates
Zabbix 7.4 introduces multiple new templates

The post What’s new in Zabbix 7.4 appeared first on Zabbix Blog.

Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/build-the-highest-resilience-apps-with-multi-region-strong-consistency-in-amazon-dynamodb-global-tables/

While tens of thousands of customers are successfully using Amazon DynamoDB global tables with eventual consistency, we’re seeing emerging needs for even stronger resilience. Many organizations find that the DynamoDB multi-Availability Zone architecture and eventually consistent global tables meet their requirements, but critical applications like payment processing systems and financial services demand more.

For these applications, customers require a zero Recovery Point Objective (RPO) during rare Region-wide events, meaning you can direct your app to read the latest data from any Region. Your multi-Region applications always need to access the same data regardless of location.

Starting today, you can use a new Amazon DynamoDB global tables capability that provides multi-Region strong consistency (MRSC), enabling zero RPO. This capability, first announced as a preview at AWS re:Invent 2024, simplifies building highly resilient global applications.

Here’s how you can enable MRSC starting with an existing empty DynamoDB table:

With MRSC, DynamoDB now offers you the highest level of resilience for your applications. If application processing is interrupted in a Region, you can redirect traffic to another Region containing a MRSC replica and know that you’ll be processing the latest data.

Getting started
Let me walk you through how you can use this new capability.

To start using MRSC, I need to create a global table from an existing DynamoDB table that doesn’t contain any data. I navigate to my existing table, select the Global tables tab and select Create replica.

The MRSC availability architecture requires three AWS Regions. I can configure MRSC with either three full replicas or with two replicas and a witness. A witness contains only replicated change data to provide the required availability without maintaining a full copy of my table data.

The following screenshot shows how I configure MRSC with two replicas and a witness. To configure MRSC with three full replicas instead, I can clear Configure Region 2 as Witness.

If I need to update my existing table programmatically, I can use the Amazon Q CLI to generate the required command with the following prompt:

> Hey Q! Update my existing DynamoDB table called "demo-mrsc" in us-east-1 with multi-Region strong consistency across us-east-2 with witness in us-west-2 Regions

Shortly after, Q CLI will respond back with following command:

> To update your DynamoDB table with multi-Region strong consistency, you'll need to use the update-table command with the appropriate parameters. Here's how you would do it:

aws dynamodb update-table \ 
    --table-name demo-mrsc \ 
    --replica-updates '[{"Create": {"RegionName": "us-east-2"}}]' \ 
    --global-table-witness-updates '[{"Create": {"RegionName": "us-west-2"}}]' \ 
    --multi-region-consistency STRONG \ 
    --region us-east-1

After it’s finished processing, I can check the status of my MRSC global table. I can see I have a witness configured for my DynamoDB global table. A witness reduces costs while still providing the resilience benefits of multi-Region strong consistency.

Then, in my application, I can use ConsistentRead to read data with strong consistency. Here’s a Python example:

import boto3

# Configure the DynamoDB client for your region
dynamodb = boto3.resource('dynamodb', region_name='us-east-2')
table = dynamodb.Table('demo-mrsc')

pk_id = "demo#test123"

# Read with strong consistency across regions
response = table.get_item(
    Key={
        'PK': pk_id
    },
    ConsistentRead=True
)

print(response)

For operations that require the strongest resilience, I can use ConsistentRead=True. For less critical operations where eventual consistency is acceptable, I can omit this parameter to improve performance and reduce costs.

Additional things to know
Here are a couple of things to note:

  • Availability – The Amazon DynamoDB multi-Region strong consistency capability is available in following AWS Regions: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Osaka, Seoul, Tokyo), and Europe (Frankfurt, Ireland, London, Paris)
  • Pricing – Multi-Region strong consistency pricing follows the existing global tables pricing structure. DynamoDB recently reduced global tables pricing by up to 67 percent, making this highly resilient architecture more affordable than ever. Visit Amazon DynamoDB lowers pricing for on-demand throughput and global tables in the AWS Database Blog to learn more.

Learn more about how you can achieve the highest level of application resilience, enable your applications to be always available and always read the latest data regardless of the Region by visiting Amazon DynamoDB global tables.

Happy building!

— Donnie


New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c8gn-instances-powered-by-aws-graviton4-offering-up-to-600gbps-network-bandwidth/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C8gn network optimized instances powered by AWS Graviton4 processors and the latest 6th generation AWS Nitro Card. EC2 C8gn instances deliver up to 600Gbps network bandwidth, the highest bandwidth among EC2 network optimized instances.

You can use C8gn instances to run the most demanding network intensive workloads, such as security and network virtual appliances (virtual firewalls, routers, load balancers, proxy servers, DDoS appliances), data analytics, and tightly-coupled cluster computing jobs.

EC2 C8gn instances specifications
C8gn instances provide up to 192 vCPUs and 384 GiB memory, and offer up to 30 percent higher compute performance compared Graviton3-based EC2 C7gn instances.

Here are the specs for C8gn instances:

Instance Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
c8gn.medium 1 2 Up to 25 Up to 10
c8gn.large 2 4 Up to 30 Up to 10
c8gn.xlarge 4 8 Up to 40 Up to 10
c8gn.2xlarge 8 16 Up to 50 Up to 10
c8gn.4xlarge 16 32 50 10
c8gn.8xlarge 32 64 100 20
c8gn.12xlarge 48 96 150 30
c8gn.16xlarge 64 128 200 40
c8gn.24xlarge 96 192 300 60
c8gn.metal-24xl 96 192 300 60
c8gn.48xlarge 192 384 600 60
c8gn.metal-48xl 192 384 600 60

You can launch C8gn instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.

If you’re using C7gn instances now, you will have straightforward experience migrating network intensive workloads to C8gn instances because the new instances offer similar vCPU and memory ratios. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types.

You can also visit the Level up your compute with AWS Graviton page to begin your Graviton adoption journey.

Now available
Amazon EC2 C8gn instances are available today in US East (N. Virginia) and US West (Oregon) Regions. Two metal instance sizes are only available in US East (N. Virginia) Region. These instances can be purchased as On-Demand, Savings Plan, Spot instances, or as Dedicated instances and Dedicated hosts.

Give C8gn instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 C8g instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: Project Rainier, Amazon CloudWatch investigations, AWS MCP servers, and more (June 30, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-project-rainier-amazon-cloudwatch-investigations-aws-mcp-servers-and-more-june-30-2025/

Every time I visit Seattle, the first thing that greets me at the airport is Mount Rainier. Did you know that the most innovative project at Amazon Web Services (AWS) is named after this mountain?

Project Rainier is a new project to create what is expected to be the world’s most powerful computer for training AI models across multiple data centers in the United Stages. Anthropic will develop the advanced versions of its Claude models with five times more computing power than its current largest training cluster.

The key technology powering Project Rainier is AWS custom-designed Trainium2 chips, which are specialized for the immense data processing required to train complex AI models. Thousands of these Trainium2 chips will be connected in a new type of Amazon EC2 UltraServer and EC2 UltraCluster architecture that allows ultra-fast communication and data sharing across the massive system.

Learn about the AWS vertical integration of Project Rainer, where it designs every component of the technology stack from chips to software, allows it to optimize the entire system for maximum efficiency and reliability.

Last week’s launches
Here are some launches that got my attention:

  • Amazon S3 access for Amazon FSx for OpenZFS – You can access and analyze your FSx for OpenZFS file data through Amazon S3 Access Points, enabling seamless integration with AWS AI/ML, and analytics services without moving your data out of the file system. You can treat your FSx for OpenZFS data as if it were stored in S3, making it accessible through the S3 API for various applications including Amazon Bedrock, Amazon SageMaker, AWS Glue, and other S3 based cloud-native applications.
  • Amazon S3 with sort and z-order compaction for Apache Iceberg tables – You can optimize query performance and reduce costs with new sort and z-order compaction. With S3 Tables, sort compaction automatically organizes data files based on defined column orders, while z-order compaction can be enabled through the maintenance API for efficient multicolumn queries.
  • Amazon CloudWatch investigations – You can accelerate your operational troubleshooting in AWS environments using the Amazon CloudWatch AI-powered investigation feature, which helps identify anomalies, surface related signals, and suggest remediation steps. This capability can be initiated through CloudWatch data widgets, multiple AWS consoles, CloudWatch alarm actions, or Amazon Q chat and enables team collaboration and integration with Slack and Microsoft Teams.
  • Amazon Bedrock Guardrails Standard tier – You can enhance your AI content safety measures using the new Standard tier. It offers improved content filtering and topic denial capabilities across up to 60 languages, better detection of variations including typos, and stronger protection against prompt attacks. This feature lets you configure safeguards to block harmful content, prevent model hallucinations, redact personally identifiable information (PII), and verify factual claims through automated reasoning checks.
  • Amazon Route 53 Resolver endpoints for private hosted zone – You can simplify DNS management across AWS and on-premises infrastructure using the new Route 53 DNS delegation feature for private hosted zone subdomains, which works with both inbound and outbound Resolver endpoints. You can delegate subdomain authority between your on-premises infrastructure and Route 53 Resolver cloud service using name server records, eliminating the need for complex conditional forwarding rules.
  • Amazon Q Developer CLI for Java transformation – You can automate and scale Java application upgrades using the new Amazon Q Developer Java transformation command line interface (CLI). This feature perform upgrades from Java versions 8, 11, 17, or 21 to versions 17 or 21 directly from the command line. This tool offers selective transformation options so you can choose specific steps from transformation plans and customize library upgrades.
  • New AWS IoT Device Management managed integrations – You can simplify Internet of Things (IoT) device management across multiple manufacturers and protocols using the new managed integrations feature, which provides a unified interface for controlling devices whether they connect directly, through hubs or third-party clouds. The feature includes pre-built cloud-to-cloud (C2C) connectors, device data model templates, and SDKs that support ZigBee, Z-Wave, and Wi-Fi protocols, while you can still create custom connectors and data models.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Various Model Context Protocol (MCP) servers for AWS services have been released. Here are some tutorials about MCP servers that you might find interesting:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS NY Summits – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Amazon FSx for OpenZFS now supports Amazon S3 access without any data movement

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/amazon-fsx-for-openzfs-now-supports-amazon-s3-access-without-any-data-movement/

Starting today, you can attach Amazon S3 Access Points to your Amazon FSx for OpenZFS file systems to access your file data as if it were in Amazon Simple Storage Service (Amazon S3). With this new capability, your data in FSx for OpenZFS is accessible for use with a broad range of Amazon Web Services (AWS) services and applications for artificial intelligence, machine learning (ML), and analytics that work with S3. Your file data continues to reside in your FSx for OpenZFS file system.

Organizations store hundreds of exabytes of file data on premises and want to move this data to AWS for greater agility, reliability, security, scalability, and reduced costs. Once their file data is in AWS, organizations often want to do even more with it. For example, they want to use their enterprise data to augment generative AI applications and build and train machine learning models with the broad spectrum of AWS generative AI and machine learning services. They also want the flexibility to use their file data with new AWS applications. However, many AWS data analytics services and applications are built to work with data stored in Amazon S3 as data lakes. After migration, they can use tools that work with Amazon S3 as their data source. Previously, this required data pipelines to copy data between Amazon FSx for OpenZFS file systems and Amazon S3 buckets.

Amazon S3 Access Points attached to FSx for OpenZFS file systems remove data movement and copying requirements by maintaining unified access through both file protocols and Amazon S3 API operations. You can read and write file data using S3 object operations including GetObject, PutObject, and ListObjectsV2. You can attach hundreds of access points to a file system, with each S3 access point configured with application-specific permissions. These access points support the same granular permissions controls as S3 access points that attach to S3 buckets, including AWS Identity and Access Management (IAM) access point policies, Block Public Access, and network origin controls such as restricting access to your Virtual Private Cloud (VPC). Because your data continues to reside in your FSx for OpenZFS file system, you continue to access your data using Network File System (NFS) and benefit from existing data management capabilities.

You can use your file data in Amazon FSx for OpenZFS file systems to power generative AI applications with Amazon Bedrock for Retrieval Augmented Generation (RAG) workflows, train ML models with Amazon SageMaker, and run analytics or business intelligence (BI) with Amazon Athena and AWS Glue as if the data were in S3, using the S3 API. You can also generate insights using open source tools such as Apache Spark and Apache Hive, without moving or refactoring your data.

To get started
You can create and attach an S3 Access Point to your Amazon FSx for OpenZFS file system using the Amazon FSx console, the AWS Command Line Interface (AWS CLI), or the AWS SDK.

To start, you can follow the steps in the Amazon FSx for OpenZFS file system documentation page to create the file system, then, using the Amazon FSx console, go to Actions and select Create S3 access point. Leave the standard configuration and then create.

To monitor the creation progress, you can go to the Amazon FSx console.

Once available, choose the name of the new S3 access point and review the access point summary. This summary includes an automatically generated alias that works anywhere you would normally use S3 bucket names.

Using the bucket-style alias, you can access the FSx data directly through S3 API operations.

  • List objects using the ListObjectsV2 API

  • Get files using the GetObject API

  • Write data using the PutObject API

The data continues to be accessible via NFS.

Beyond accessing your FSx data through the S3 API, you can work with your data using the broad range of AI, ML, and analytics services that work with data in S3. For example, I built an Amazon Bedrock Knowledge Base using PDFs containing airline customer service information from my travel support application repository, WhatsApp-Powered RAG Travel Support Agent: Elevating Customer Experience with PostgreSQL Knowledge Retrieval, as the data source.

To create the Amazon Bedrock Knowledge Base, I followed the connection steps in Connect to Amazon S3 for your knowledge base user guide. I chose Amazon S3 as the data source, entered my S3 access point alias as the S3 source, then configured and created the knowledge base.

Once the knowledge base is synchronized, I can see all documents and the Document source as S3.

Finally, I ran queries against the knowledge base and verified that it successfully used the file data from my Amazon FSx for OpenZFS file system to provide contextual answers, demonstrating seamless integration without data movement.

Things to know
Integration and access control – Amazon S3 Access Points for Amazon FSx for OpenZFS file systems support standard S3 API operations (such as GetObject, ListObjectsV2, PutObject) through the S3 endpoint, with granular access controls through AWS Identity and Access Management (IAM) permissions and file system user authentication. Your S3 Access Point includes an automatically generated access point alias for data access using S3 bucket names, and public access is blocked by default for Amazon FSx resources.

Data management – Your data stays in your Amazon FSx for OpenZFS file system while becoming accessible as if it were in Amazon S3, eliminating the need for data movement or copies, with file data remaining accessible through NFS file protocols.

Performance – Amazon S3 Access Points for Amazon FSx for OpenZFS file systems deliver first-byte latency in the tens of milliseconds range, consistent with S3 bucket access. Performance scales with your Amazon FSx file system’s provisioned throughput, with maximum throughput determined by your underlying FSx file system configuration.

Pricing – You’re billed by Amazon S3 for the requests and data transfer costs through your S3 Access Point, in addition to your standard Amazon FSx charges. Learn more on the Amazon FSx for OpenZFS pricing page.

You can get started today using the Amazon FSx console, AWS CLI, or AWS SDK to attach Amazon S3 Access Points to your Amazon FSx for OpenZFS file systems. The feature is available in the following AWS Regions: US East (N. Virginia, Ohio), US West (Oregon), Europe (Frankfurt, Ireland, Stockholm), and Asia Pacific (Hong Kong, Singapore, Sydney, Tokyo).

— Eli

New: Improve Apache Iceberg query performance in Amazon S3 with sort and z-order compaction

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/new-improve-apache-iceberg-query-performance-in-amazon-s3-with-sort-and-z-order-compaction/

You can now use sort and z-order compaction to improve Apache Iceberg query performance in Amazon S3 Tables and general purpose S3 buckets.

You typically use Iceberg to manage large-scale analytical datasets in Amazon Simple Storage Service (Amazon S3) with AWS Glue Data Catalog or with S3 Tables. Iceberg tables support use cases such as concurrent streaming and batch ingestion, schema evolution, and time travel. When working with high-ingest or frequently updated datasets, data lakes can accumulate many small files that impact the cost and performance of your queries. You’ve shared that optimizing Iceberg data layout is operationally complex and often requires developing and maintaining custom pipelines. Although the default binpack strategy with managed compaction provides notable performance improvements, introducing sort and z-order compaction options for both S3 and S3 Tables delivers even greater gains for queries filtering across one or more dimensions.

Two new compaction strategies: Sort and z-order
To help organize your data more efficiently, Amazon S3 now supports two new compaction strategies: sort and z-order, in addition to the default binpack compaction. These advanced strategies are available for both fully managed S3 Tables and Iceberg tables in general purpose S3 buckets through AWS Glue Data Catalog optimizations.

Sort compaction organizes files based on a user-defined column order. When your tables have a defined sort order, S3 Tables compaction will now use it to cluster similar values together during the compaction process. This improves the efficiency of query execution by reducing the number of files scanned. For example, if your table is organized by sort compaction along state and zip_code, queries that filter on those columns will scan fewer files, improving latency and reducing query engine cost.

Z-order compaction goes a step further by enabling efficient file pruning across multiple dimensions. It interleaves the binary representation of values from multiple columns into a single scalar that can be sorted, making this strategy particularly useful for spatial or multidimensional queries. For example, if your workloads include queries that simultaneously filter by pickup_location, dropoff_location, and fare_amount, z-order compaction can reduce the total number of files scanned compared to traditional sort-based layouts.

S3 Tables use your Iceberg table metadata to determine the current sort order. If a table has a defined sort order, no additional configuration is needed to activate sort compaction—it’s automatically applied during ongoing maintenance. To use z-order, you need to update the table maintenance configuration using the S3 Tables API and set the strategy to z-order. For Iceberg tables in general purpose S3 buckets, you can configure AWS Glue Data Catalog to use sort or z-order compaction during optimization by updating the compaction settings.

Only new data written after enabling sort or z-order will be affected. Existing compacted files will remain unchanged unless you explicitly rewrite them by increasing the target file size in table maintenance settings or rewriting data using standard Iceberg tools. This behavior is designed to give you control over when and how much data is reorganized, balancing cost and performance.

Let’s see it in action
I’ll walk you through a simplified example using Apache Spark and the AWS Command Line Interface (AWS CLI). I have a Spark cluster installed and an S3 table bucket. I have a table named testtable in a testnamespace. I temporarily disabled compaction, the time for me to add data into the table.

After adding data, I check the file structure of the table.

spark.sql("""
  SELECT 
    substring_index(file_path, '/', -1) as file_name,
    record_count,
    file_size_in_bytes,
    CAST(UNHEX(hex(lower_bounds[2])) AS STRING) as lower_bound_name,
    CAST(UNHEX(hex(upper_bounds[2])) AS STRING) as upper_bound_name
  FROM ice_catalog.testnamespace.testtable.files
  ORDER BY file_name
""").show(20, false)
+--------------------------------------------------------------+------------+------------------+----------------+----------------+
|file_name                                                     |record_count|file_size_in_bytes|lower_bound_name|upper_bound_name|
+--------------------------------------------------------------+------------+------------------+----------------+----------------+
|00000-0-66a9c843-5a5c-407f-8da4-4da91c7f6ae2-0-00001.parquet  |1           |837               |Quinn           |Quinn           |
|00000-1-b7fa2021-7f75-4aaf-9a24-9bdbb5dc08c9-0-00001.parquet  |1           |824               |Tom             |Tom             |
|00000-10-00a96923-a8f4-41ba-a683-576490518561-0-00001.parquet |1           |838               |Ilene           |Ilene           |
|00000-104-2db9509d-245c-44d6-9055-8e97d4e44b01-0-00001.parquet|1000000     |4031668           |Anjali          |Tom             |
|00000-11-27f76097-28b2-42bc-b746-4359df83d8a1-0-00001.parquet |1           |838               |Henry           |Henry           |
|00000-114-6ff661ca-ba93-4238-8eab-7c5259c9ca08-0-00001.parquet|1000000     |4031788           |Anjali          |Tom             |
|00000-12-fd6798c0-9b5b-424f-af70-11775bf2a452-0-00001.parquet |1           |852               |Georgie         |Georgie         |
|00000-124-76090ac6-ae6b-4f4e-9284-b8a09f849360-0-00001.parquet|1000000     |4031740           |Anjali          |Tom             |
|00000-13-cb0dd5d0-4e28-47f5-9cc3-b8d2a71f5292-0-00001.parquet |1           |845               |Olivia          |Olivia          |
|00000-134-bf6ea649-7a0b-4833-8448-60faa5ebfdcd-0-00001.parquet|1000000     |4031718           |Anjali          |Tom             |
|00000-14-c7a02039-fc93-42e3-87b4-2dd5676d5b09-0-00001.parquet |1           |838               |Sarah           |Sarah           |
|00000-144-9b6d00c0-d4cf-4835-8286-ebfe2401e47a-0-00001.parquet|1000000     |4031663           |Anjali          |Tom             |
|00000-15-8138298d-923b-44f7-9bd6-90d9c0e9e4ed-0-00001.parquet |1           |831               |Brad            |Brad            |
|00000-155-9dea2d4f-fc98-418d-a504-6226eb0a5135-0-00001.parquet|1000000     |4031676           |Anjali          |Tom             |
|00000-16-ed37cf2d-4306-4036-98de-727c1fe4e0f9-0-00001.parquet |1           |830               |Brad            |Brad            |
|00000-166-b67929dc-f9c1-4579-b955-0d6ef6c604b2-0-00001.parquet|1000000     |4031729           |Anjali          |Tom             |
|00000-17-1011820e-ee25-4f7a-bd73-2843fb1c3150-0-00001.parquet |1           |830               |Noah            |Noah            |
|00000-177-14a9db71-56bb-4325-93b6-737136f5118d-0-00001.parquet|1000000     |4031778           |Anjali          |Tom             |
|00000-18-89cbb849-876a-441a-9ab0-8535b05cd222-0-00001.parquet |1           |838               |David           |David           |
|00000-188-6dc3dcca-ddc0-405e-aa0f-7de8637f993b-0-00001.parquet|1000000     |4031727           |Anjali          |Tom             |
+--------------------------------------------------------------+------------+------------------+----------------+----------------+
only showing top 20 rows

I observe the table is made of multiple small files and that the upper and lower bounds for the new files have overlap–the data is certainly unsorted.

I set the table sort order.

spark.sql("ALTER TABLE ice_catalog.testnamespace.testtable WRITE ORDERED BY name ASC")

I enable table compaction (it’s enabled by default; I disabled it at the start of this demo)

aws s3tables put-table-maintenance-configuration --table-bucket-arn ${S3TABLE_BUCKET_ARN} --namespace testnamespace --name testtable --type icebergCompaction --value "status=enabled,settings={icebergCompaction={strategy=sort}}"

Then, I wait for the next compaction job to trigger. These run throughout the day, when there are enough small files. I can check the compaction status with the following command.

aws s3tables get-table-maintenance-job-status --table-bucket-arn ${S3TABLE_BUCKET_ARN} --namespace testnamespace --name testtable

When the compaction is done, I inspect the files that make up my table one more time. I see that the data was compacted to two files, and the upper and lower bounds show that the data was sorted across these two files.

spark.sql("""
  SELECT 
    substring_index(file_path, '/', -1) as file_name,
    record_count,
    file_size_in_bytes,
    CAST(UNHEX(hex(lower_bounds[2])) AS STRING) as lower_bound_name,
    CAST(UNHEX(hex(upper_bounds[2])) AS STRING) as upper_bound_name
  FROM ice_catalog.testnamespace.testtable.files
  ORDER BY file_name
""").show(20, false)
+------------------------------------------------------------+------------+------------------+----------------+----------------+
|file_name                                                   |record_count|file_size_in_bytes|lower_bound_name|upper_bound_name|
+------------------------------------------------------------+------------+------------------+----------------+----------------+
|00000-4-51c7a4a8-194b-45c5-a815-a8c0e16e2115-0-00001.parquet|13195713    |50034921          |Anjali          |Kelly           |
|00001-5-51c7a4a8-194b-45c5-a815-a8c0e16e2115-0-00001.parquet|10804307    |40964156          |Liza            |Tom             |
+------------------------------------------------------------+------------+------------------+----------------+----------------+

There are fewer files, they have larger sizes, and there is a better clustering across the specified sort column.

To use z-order, I follow the same steps, but I set strategy=z-order in the maintenance configuration.

Regional availability
Sort and z-order compaction are now available in all AWS Regions where Amazon S3 Tables are supported and for general purpose S3 buckets where optimization with AWS Glue Data Catalog is available. There is no additional charge for S3 Tables beyond existing usage and maintenance fees. For Data Catalog optimizations, compute charges apply during compaction.

With these changes, queries that filter on the sort or z-order columns benefit from faster scan times and reduced engine costs. In my experience, depending on my data layout and query patterns, I observed performance improvements of threefold or more when switching from binpack to sort or z-order. Tell us how much your gains are on your actual data.

To learn more, visit the Amazon S3 Tables product page or review the S3 Tables maintenance documentation. You can also start testing the new strategies on your own tables today using the S3 Tables API or AWS Glue optimizations.

— seb