Tag Archives: news

AWS Week in Review – March 7, 2022

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/aws-week-in-review-march-7-2022/

This post is part of our Week in Review series. Check back each week for a quick round up of interesting news and announcements from AWS!

Hello Again
The AWS Week in Review is back! Many years ago, I tried to write a weekly post that captured the most significant AWS activity. This was easy at first but quickly grew to consume a good fraction of a working day. After a lot of thought and planning, we are making a fresh start with the goal of focusing on some of the most significant AWS launches of the previous week. Each week, one member of the AWS News Blog team will write and publish a post similar to this one. We will do our best to make sure that our effort is scalable and sustainable.

Last Week’s Launches
Here are some launches that caught my eye last week:

AWS Health Dashboard – This new destination brings together the AWS Service Health Dashboard and the Personal Health Dashboard into a single connected experience. You get a more responsive and accurate view, better usability, and greater operational resilience. The new page is mobile-friendly and follows the latest AWS design standard. It includes a searchable history of events, fast page-load times, and automatic in-line refresh. It also provides a more responsive view when multiple AWS services are affected by a common underlying root cause. To learn more, read the blog post or just visit the AWS Health Dashboard.

AWS DeepRacer Student Virtual League – High school and undergraduate students 16 and older can now compete in the DeepRacer Student Virtual League for the chance to win prizes, glory, and a trip to AWS re:Invent 2022 in Las Vegas. The student league provides access to dozens of hours of free machine learning model training, along with educational materials that cover the theoretical and practical aspects of machine learning. Competitions run monthly until September 30; the top participants each month qualify for the Global AWS DeepRacer Student League Championships in October. To learn more, read the What’s New or visit AWS DeepRacer Student.

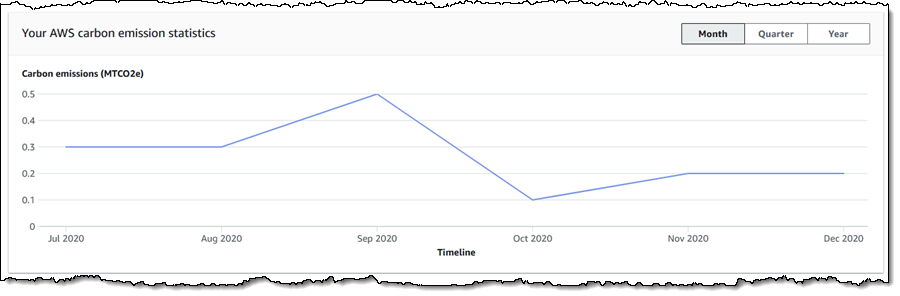
Customer Carbon Footprint Tool – This tool will help you to learn more about the carbon footprint of your cloud infrastructure, and will help you to meet your goals for sustainability. It is part of the AWS Billing console, and is available to all AWS customers at no cost. When you open the tool, you will see your carbon emissions in several forms, all with month-level granularity. You can also see your carbon emission statistics on a monthly, quarterly, or annual basis. To learn more, read my blog post.

RDS Multi-AZ Deployment Option – You can now take advantage of a new Amazon RDS deployment option that has a footprint in three AWS Availability Zones and gives you up to 2x faster transaction commit latency, automated failovers that typically take 35 seconds or less, and readable standby instances. This new option takes advantage of Graviton2 processors and fast NVME SSD storage; to learn more, read Seb’s blog post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Serverless Architecture Book – The second edition of Serverless Architectures on AWS is now available.

AWS Cookbook – AWS Cookbook: Recipes for Success on AWS is now available.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS Pi Day (March 14) – We have an entire day of online content to celebrate 16 years of innovation with Amazon S3. Sessions will cover data protection, security, compliance, archiving, data lakes, backup, and more. Sign up today, and I will see you there!

.NET Application Modernization Webinar (March 23) – Learn about .NET modernization, what it is, and why you might want to modernize. See a deep dive that focuses on the AWS Microservice Extractor for .NET. Sign up today.

And that’s all for this week. Leave me a comment and let me know if this was helpful to you!

— Jeff;

Russia-Ukraine Cybersecurity Updates

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/03/04/russia-ukraine-cybersecurity-updates/

Russia-Ukraine Cybersecurity Updates

Cyberattacks are a distinct concern in the Russia-Ukraine conflict, with the potential to impact individuals and organizations far beyond the physical frontlines. With events unfolding rapidly, we want to provide a single channel by which we can communicate to the security community the major cyber-related developments from the conflict each day.

Each business day, we will update this blog at 5 pm EST with what we believe are the need-to-know updates in cybersecurity and threat intelligence relating to the Russia-Ukraine war. We hope this blog will make it easier for you to stay current with these events during an uncertain and quickly changing time.


March 3, 2022

Additional sanctions: The US Treasury Dept. announced another round of sanctions on Russian elites, as well as many organizations it characterized as outlets of disinformation and propaganda.

Public policy: The Russia-Ukraine conflict is adding momentum to cybersecurity regulatory actions. Most recently, that includes

  • Incident reporting law: Citing the need to defend against potential retaliatory attacks from Russia, the US Senate passed a bill to require critical infrastructure owners and operators to report significant cybersecurity incidents to CISA, as well as ransomware payments. The US House is now considering fast-tracking this bill, which means it may become law quite soon.
  • FCC inquiry on BGP security: “[E]specially in light of Russia’s escalating actions inside of Ukraine,” FCC seeks comment on vulnerabilities threatening the Border Gateway Protocol (BGP) that is central to the Internet’s global routing system.

CISA threat advisory: CISA recently reiterated that it has no specific, credible threat against the U.S. at this time. It continues to point to its Shields Up advisory for resources and updates related to the Russia-Ukraine conflict.

Threat Intelligence Update

  • An Anonymous-affiliated hacking group claims to have hacked a branch Russian Military and Rosatom, the Russian State Atomic Energy Corporation.

The hacktivist group Anonymous and its affiliate have hacked and leaked access to the phone directory of the military prosecutor’s office of the southern military district of Russia, as well as documents from the Rosatom State Atomic Energy Corporation.

Available in Threat Library as: OpRussia 2022 (for Threat Command customers who want to learn more)

  • A threat actor supporting Russia claims to have hacked and leaked sensitive information related to the Ukrainian military.

The threat actor “Lenovo” claims to have hacked a branch of the Ukrainian military and leaked confidential information related to its soldiers. The information was published on an underground Russian hacking forum.

Source: XSS forum (discovered by our threat hunters on the dark web)

  • An Anonymous hacktivist associated group took down the popular Russian news website lenta.ru

As part of the OpRussia cyber-attack campaign, an Anonymous hacktivist group known as “El_patron_real” took down one of the most popular Russian news websites, lenta.ru. As of Thursday afternoon, March 3, the website is still down.

Available in Threat Library as: El_patron_real (for Threat Command customers who want to learn more)

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

New Amazon RDS for MySQL & PostgreSQL Multi-AZ Deployment Option: Improved Write Performance & Faster Failover

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-rds-multi-az-db-cluster/

Today, we are announcing a new Amazon Relational Database Service (RDS) Multi-AZ deployment option with up to 2x faster transaction commit latency, automated failovers typically under 35 seconds, and readable standby instances.

Amazon RDS offers two replication options to enhance availability and performance:

  • Multi-AZ deployments gives high availability and automatic failover. Amazon RDS creates a storage-level replica of the database in a second Availability Zone. It then synchronously replicates data from the primary to the standby DB instance for high availability. The primary DB instance serves application requests, while the standby DB instance remains ready to take over in case of a failure. Amazon RDS manages all aspects of failure detection, failover, and repair actions so the applications using the database can be highly available.
  • Read replicas allow applications to scale their read operations across multiple database instances. The database engine replicates data asynchronously to the read replicas. The application sends the write requests (INSERT, UPDATE, and DELETE) to the primary database, and read requests (SELECT) can be load balanced across read replicas. In case of failure of the primary node, you can manually promote a read replica to become the new primary database.

Multi-AZ deployments and read replicas serve different purposes. Multi-AZ deployments give your application high availability, durability, and automatic failover. Read replicas give your applications read scalability.

But what about applications that require both high availability with automatic failover and read scalability?

Introducing the New Amazon RDS Multi-AZ Deployment Option With Two Readable Standby Instances.
Starting today, we’re adding a new option to deploy RDS databases. This option combines automatic failover and read replicas: Amazon RDS Multi-AZ with two readable standby instances. This deployment option is available for MySQL and PostgreSQL databases. This is a database cluster with one primary and two readable standby instances. It provides up to 2x faster transaction commit latency and automated failovers, typically under 35 seconds.

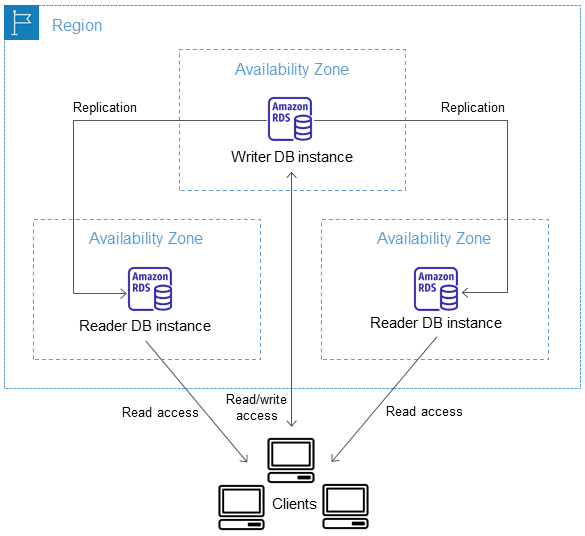
The following diagram illustrates such a deployment:

Three AZ RDS databases

When the new Multi-AZ DB cluster deployment option is enabled, RDS configures a primary database and two read replicas in three distinct Availability Zones. It then monitors and enables failover in case of failure of the primary node.

Just like with traditional read replicas, the database engine replicates data between the primary node and the read replicas. And just like with the Multi-AZ one standby deployment option, RDS automatically detects and manages failover for high availability.

You do not have to choose between high availability or scalability; Multi-AZ DB cluster with two readable standby enables both.

What Are the Benefits?
This new deployment option offers you four benefits over traditional multi-AZ deployments: improved commit latency, faster failover, readable standby instances, and optimized replications.

First, write operations are faster when using Multi-AZ DB cluster. The new Multi-AZ DB cluster instances leverage M6gd and R6gd instance types. These instances are powered by AWS Graviton2 processors. They are equipped with fast NVMe SSD for local storage, ideal for high speed and low-latency storage. They deliver up to 40 percent better price performance and 50 percent more local storage GB per vCPU over comparable x86-based instances.

Multi-AZ DB instances use Amazon Elastic Block Store (EBS) to store the data and the transaction log. The new Multi-AZ DB cluster instances use local storage provided by the instances to store the transaction log. Local storage is optimized to deliver low-latency, high I/O operations per second (IOPS) to applications. Write operations are first written to the local storage transaction log, then flushed to permanent storage on database storage volumes.

Second, failover operations are typically faster than in the Multi-AZ DB instance scenario. The read replicas created by the new Multi-AZ DB cluster are full-fledged database instances. The system is designed to fail over as quickly as 35 seconds, plus the time to apply any pending transaction log. In case of failover, the system is fully automated to promote a new primary and reconfigure the old primary as a new reader instance.

Third, the two standby instances are hot standbys. Your applications may use the cluster reader endpoint to send their read requests (SELECT) to these standby instances. It allows your application to spread the database read load equally between the instances of the database cluster.

And finally, leveraging local storage for transaction log optimizes replication. The existing Multi-AZ DB instance replicates all changes at storage-level. The new Multi-AZ DB cluster replicates only the transaction log and uses a quorum mechanism to confirm at least one standby acknowledged the change. Database transactions are committed synchronously when one of the secondary instances confirms the transaction log is written on its local disk.

Migrating Existing Databases
For those of you having existing RDS databases and willing to take advantage of this new Multi-AZ DB cluster deployment option, you may take a snapshot of your database to create a storage-level backup of your existing database instance. Once the snapshot is ready, you can create a new database cluster, with Multi-AZ DB cluster deployment option, based on this snapshot. Your new Multi-AZ DB cluster will be a perfect copy of your existing database.

Let’s See It in Action
To get started, I point my browser to the AWS Management Console and navigate to RDS. The Multi-AZ DB cluster deployment option is available for MySQL version 8.0.28 or later and PostgreSQL version 13.4 R1 and 13.5 R1. I select either database engine, and I ensure the version matches the minimum requirements. The rest of the procedure is the same as a standard Amazon RDS database launch.

Under Deployment options, I select PostgreSQL, version 13.4 R1, and under Availability and Durability, I select Multi-AZ DB cluster.

Three AZ RDS launch console

If required, I may choose the set of Availability Zones RDS uses for the cluster. To do so, I create a DB subnet group and assign the cluster to this subnet group.

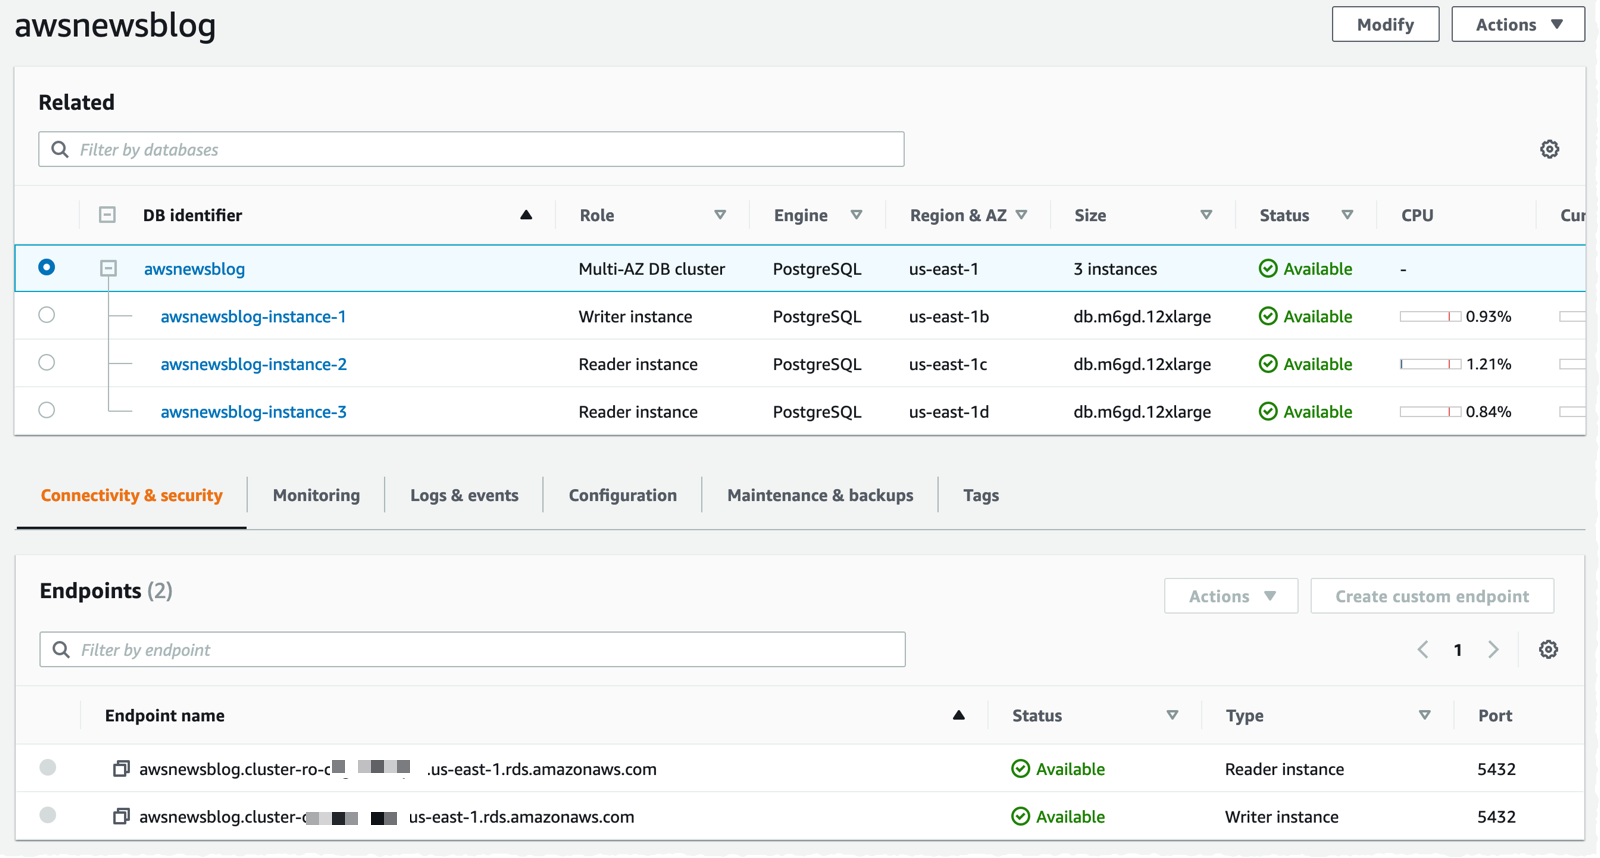
Once launched, I verify that three DB instances have been created. I also take note of the two endpoints provided by Amazon RDS: the primary endpoint and one load-balanced endpoint for the two readable standby instances.

RDS Three AZ list of instances

To test the new cluster, I create an Amazon Linux 2 EC2 instance in the same VPC, within the same security group as the database, and I make sure I attach an IAM role containing the AmazonSSMManagedInstanceCore managed policy. This allows me to connect to the instance using SSM instead of SSH.

Once the instance is started, I use SSM to connect to the instance. I install PostgreSQL client tools.

sudo amazon-linux-extras enable postgresql13
sudo yum clean metadata
sudo yum install postgresql

I connect to the primary DB. I create a table and INSERT a record.

psql -h awsnewsblog.cluster-c1234567890r.us-east-1.rds.amazonaws.com -U postgres

postgres=> create table awsnewsblogdemo (id int primary key, name varchar);
CREATE TABLE

postgres=> insert into awsnewsblogdemo (id,name) values (1, 'seb');
INSERT 0 1

postgres=> exit

To verify the replication works as expected, I connect to the read-only replica. Notice the -ro- in the endpoint name. I check the table structure and enter a SELECT statement to confirm the data have been replicated.

psql -h awsnewsblog.cluster-ro-c1234567890r.us-east-1.rds.amazonaws.com -U postgres

postgres=> \dt

              List of relations
 Schema |      Name       | Type  |  Owner
--------+-----------------+-------+----------
 public | awsnewsblogdemo | table | postgres
(1 row)

postgres=> select * from awsnewsblogdemo;
 id | name
----+------
  1 | seb
(1 row)

postgres=> exit

In the scenario of a failover, the application will be disconnected from the primary database instance. In that case, it is important that your application-level code try to reestablish network connection. After a short period of time, the DNS name of the endpoint will point to the standby instance, and your application will be able to reconnect.

To learn more about Multi-AZ DB clusters, you can refer to our documentation.

Pricing and Availability
Amazon RDS Multi-AZ deployments with two readable standbys is generally available in the following Regions: US East (N. Virginia), US West (Oregon), and Europe (Ireland). We will add more regions to this list.

You can use it with MySQL version 8.0.28 or later, or PostgreSQL version 13.4 R1 or 13.5 R1.

Pricing depends on the instance type. In US regions, on-demand pricing starts at $0.522 per hour for M6gd instances and $0.722 per hour for R6gd instances. As usual, the Amazon RDS pricing page has the details for MySQL and PostgreSQL.

You can start to use it today.

New – Customer Carbon Footprint Tool

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-customer-carbon-footprint-tool/

Carbon is the fourth-most abundant element in the universe, and is also a primary component of all known life on Earth. When combined with oxygen it creates carbon dioxide (CO2). Many industrial activities, including the burning of fossil fuels such as coal and oil, release CO2 into the atmosphere and cause climate change.

As part of Amazon’s efforts to increase sustainability and reduce carbon emissions, we co-founded The Climate Pledge in 2019. Along with the 216 other signatories to the Pledge, we are committed to reaching net-zero carbon by 2040, 10 years ahead of the Paris Agreement. We are driving carbon out of our business in a multitude of ways, as detailed on our Carbon Footprint page. When I share this information with AWS customers, they respond positively. They now understand that running their applications in AWS Cloud can help them to lower their carbon footprint by 88% (when compared to the enterprise data centers that were surveyed), as detailed in The Carbon Reduction Opportunity of Moving to Amazon Web Services, published by 451 Research.

In addition to our efforts, organizations in many industries are working to set sustainability goals and to make commitments to reach them. In order to help them to measure progress toward their goals they are implementing systems and building applications to measure and monitor their carbon emissions data.

Customer Carbon Footprint Tool
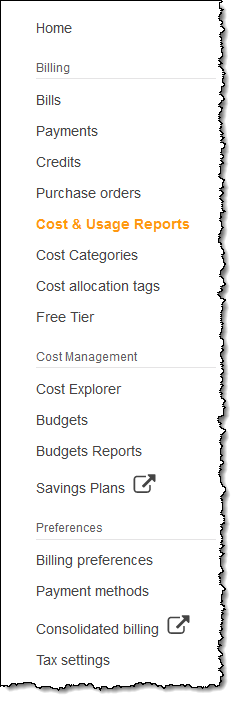
After I share information about our efforts to decarbonize with our customers, they tell me that their organization is on a similar path, and that they need to know more about the carbon footprint of their cloud infrastructure. Today I am happy to announce the new Customer Carbon Footprint Tool. This tool will help you to meet your own sustainability goals, and is available to all AWS customers at no cost. To access the calculator, I open the AWS Billing Console and click Cost & Usage Reports:

Then I scroll down to Customer Carbon Footprint Tool and review the report:

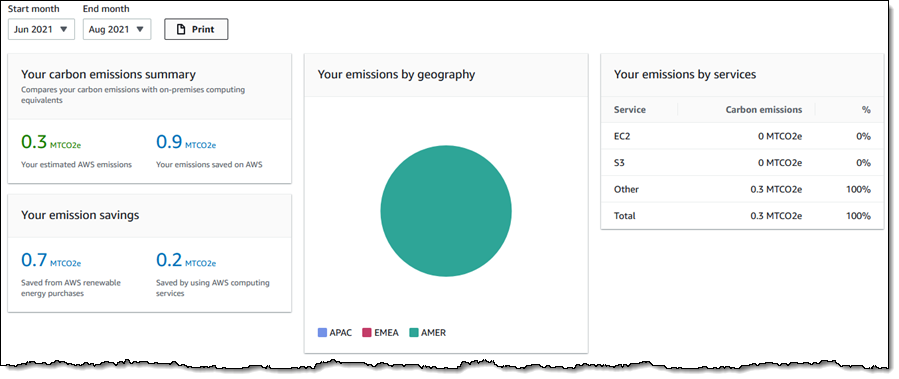
Let’s review each section. The first one allows me to select a time period with month-level granularity, and shows my carbon emissions in summary, geographic, and per-service form. In all cases, emissions are in Metric Tons of Carbon Dioxide Equivalent, abbreviated as MTCO2e:

All of the values in this section reflect the selected time period. In this example (all of which is sample data), my AWS resources emit an estimated 0.3 MTCO2e from June to August of 2021. If I had run the same application in my own facilities instead of in the AWS Cloud, I would have used an additional 0.9 MTCO2e. Of this value, 0.7 MTCO2e was saved due to renewable energy purchases made by AWS, and an additional 0.2 MTCO2e was saved due to the fact that AWS uses resources more efficiently.

I can also see my emissions by geography (all in America for this time period), and by AWS service in this section.

The second section shows my carbon emission statistics on a monthly, quarterly, or annual basis:

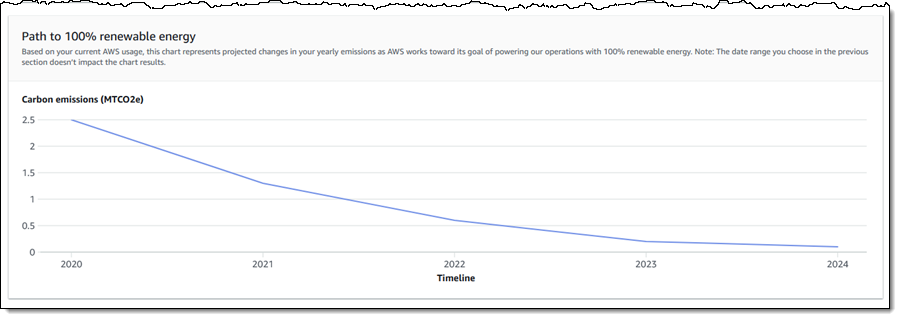
The third and final section projects how the AWS path to 100% renewable energy for our data centers will have a positive effect on my carbon emissions over time:

If you are an AWS customer, then you are already benefiting from our efforts to decarbonize and to reach 100% renewable energy usage by 2025, five years ahead of our original target.

You should also take advantage of the new Sustainability Pillar of AWS Well-Architected. This pillar contains six design principles for sustainability in the cloud, and will show you how to understand impact and to get the best utilization from the minimal number of necessary resources, while also reducing downstream impacts.

Things to Know
Here are a couple of important facts to keep in mind:

Regions – The emissions displayed reflect your AWS usage in all commercial AWS regions.

Timing – Emissions are calculated monthly. However, there is a three month delay due to the underlying billing cycle of the electric utilities that supply us with power.

Scope – The calculator shows Scope 1 and Scope 2 emissions, as defined here.

— Jeff;

Let Your IPv6-only Workloads Connect to IPv4 Services

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/let-your-ipv6-only-workloads-connect-to-ipv4-services/

Today we are announcing two new capabilities for Amazon Virtual Private Cloud (VPC) NAT gateway and Amazon Route 53, allowing your IPv6-only workloads to transparently communicate with IPV4-only services. Curious? Read on; I have details for you.

Some of you are running very large workloads involving tens of thousands of virtual machines, containers, or micro-services. To do so, you configured these workloads to work in the IPv6 address space. This avoids the problem of running out of available IPv4 addresses (a single VPC has a maximum theoretical size of 65,536 IPv4 addresses, compared to /56 ranges for IPv6, allowing for a maximum theoretical size of 2^73 -1 IPv6 addresses), and it saves you from additional headaches caused by managing complex IPv4-based networks (think about non-overlapping subnets in between VPCs belonging to multiple AWS accounts, AWS Regions, or on-premises networks).

But can you really run an IPv6 workload in isolation from the rest of the IPv4 world? Most of you told us it is important to let such workloads continue to communicate with IPv4 services, either to make calls to older APIs or just as a transient design, while you are migrating multiple dependent workloads from IPv6 to IPv4. Not having the ability to call an IPv4 service from IPv6 hosts makes migrations slower and more difficult than it needs to be. It obliged some of you to build custom solutions that are hard to maintain.

This is why we are launching two new capabilities allowing your IPv6 workloads to transparently communicate with IPv4 services: NAT64 (read “six to four”) for the VPC NAT gateway and DNS64 (also “six to four”) for the Amazon Route 53 resolver.

How Does It Work?
As illustrated by the following diagram, let’s imagine I have an Amazon Elastic Compute Cloud (Amazon EC2) instance with an IPv6-only address that has to make an API call to an IPv4 service running on another EC2 instance. In the diagram, I chose to have the IPv4-only host in a separate VPC in the same AWS account, but these capabilities work to connect to any IPv4 service, whether in the same VPC or in another AWS account’s VPC, your on-premises network, or even on the public internet. My IPv6-only host only knows the DNS name of the service.

NAT64 DNS64 beforeHere is the sequence happening when the IPv6-only host initiates a connection to the IPv4 service:

1. The IPV6 host makes a DNS call to resolve the service name to an IP address. Without DNS64, Route 53 would have returned an IPv4 address. The IPv6-only hosts would not have been able to connect to that IPv4 address. But starting today, you can turn on DNS64 for your subnet. The DNS resolver first checks if the record contains an IPv6 address (AAAA record). If it does, the IPv6 address is returned. The IPv6 host can connect to the service using just IPv6. When the record only contains an IPv4 address, the Route 53 resolver synthesizes an IPv6 address by prepending the well-known 64:ff9b::/96 prefix to the IPv4 address.

For example, when the IPv4 service has the address 34.207.250.62, Route 53 returns 64:ff9b::ffff:22cf:fa3e.

IPv6 (hexadecimal) : 64:ff9b::ffff: 22 cf fa 3e
IPv4 (decimal) : – 34 207 250 62

64:ff9b::/96is a well-known prefix defined in the RFC 6052 proposed standard to the IETF. Reading the text of the standard is a great way to fall asleep rapidly to learn all the details about IPv6 to IPv4 translation.

2. The IPv6 host initiates a connection to 64:ff9b::ffff:22cf:fa3e. You may configure subnet routing to send all packets starting with 64:ff9b::/96 to the NAT gateway. The NAT gateway recognizes the IPv6 address prefix, extracts the IPv4 address from it, and initiates an IPv4 connection to the destination. As usual, the source IPv4 address is the IPv4 address of the NAT gateway itself.

3. When the packet response arrives, the NAT gateway repopulates the destination host IPv6 address and prepends the well-known prefix 64:ff9b::/96 to the source IP address of the response packet.

Now that you understand how it works, how can you configure your VPC to take advantage of these two new capabilities?

How to Get Started
To enable these two capabilities, I have to adjust two configurations: first, I flag the subnets that require DNS64 translation, and second, I add a route to the IPv6 subnet routing table to send part of the IPv6 traffic to the NAT gateway.

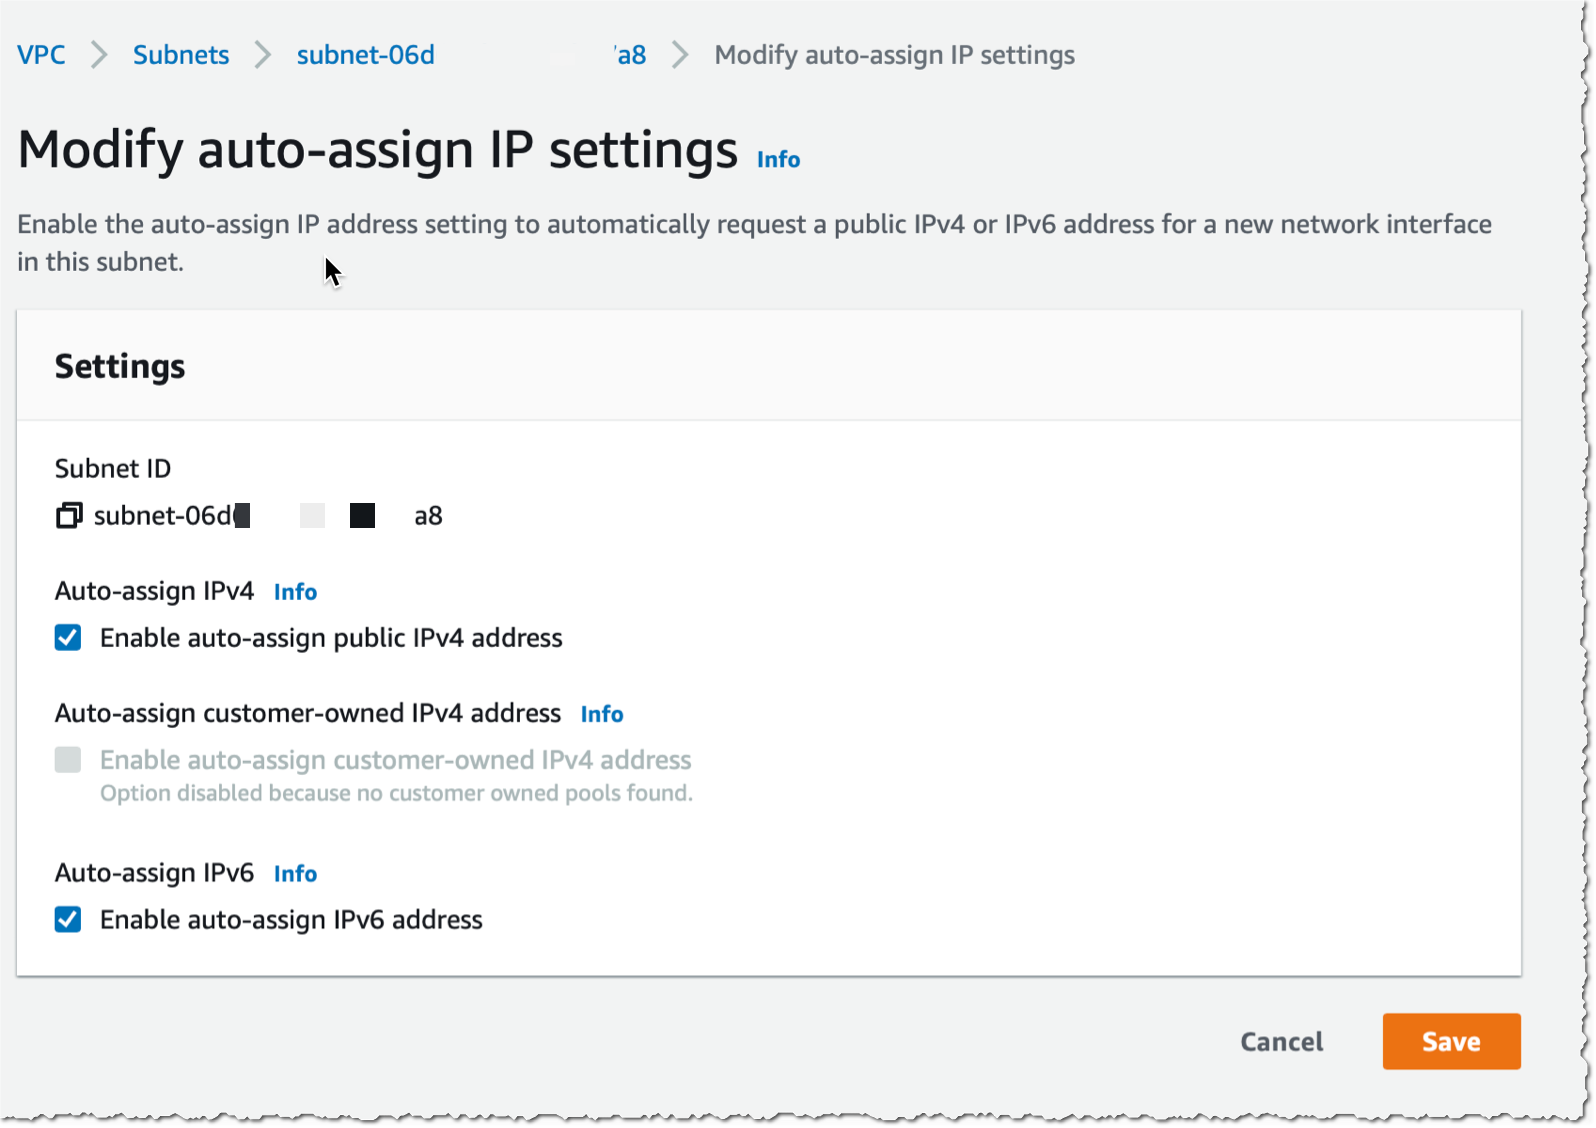
To enable DNS64, I have to use the new --enable-dns64 option to modify my existing subnets. In this demo, I use the modify-subnet-attribute command. This is a one-time operation. I can do it using the VPC API, the AWS Command Line Interface (CLI), or the AWS Management Console. Notice this is a subnet-level configuration that must be turned on explicitly. By default, the existing behavior is maintained.

aws ec2 modify-subnet-attribute --subnet-id subnet-123 --enable-dns64

I have to add a route to the subnet’s routing table to allow VPC to forward IPv6 packets prefixed by DNS64 to the NAT gateway. It tells it to route all packets with destination 64:ff9b::/96 to the NAT gateway.

aws ec2 create-route --route-table-id rtb-123 –-destination-ipv6-cidr-block 64:ff9b::/96 –-nat-gateway-id nat-123

The following diagram illustrates these two simple configuration changes.

NAT64 DNS64 afterWith these two simple changes, my IPv6-only workloads in the subnet may now communicate with IPv4 services. The IPv4 service might live in the same VPC, in another VPC, or anywhere on the internet.

You can continue to use your existing NAT gateway, and no change is required on the gateway itself or on the routing table attached to the NAT gateway subnet.

Pricing and Availability
These two new capabilities to the VPC NAT gateway and Route 53 are available today in all AWS Regions at no additional costs. Regular NAT gateway charges may apply.

Go and build your IPv6-only networks!

— seb

New – Additional Checksum Algorithms for Amazon S3

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-additional-checksum-algorithms-for-amazon-s3/

Amazon Simple Storage Service (Amazon S3) is designed to provide 99.999999999% (11 9s) of durability for your objects and for the metadata associated with your objects. You can rest assured that S3 stores exactly what you PUT, and returns exactly what is stored when you GET. In order to make sure that the object is transmitted back-and-forth properly, S3 uses checksums, basically a kind of digital fingerprint.

S3’s PutObject function already allows you to pass the MD5 checksum of the object, and only accepts the operation if the value that you supply matches the one computed by S3. While this allows S3 to detect data transmission errors, it does mean that you need to compute the checksum before you call PutObject or after you call GetObject. Further, computing checksums for large (multi-GB or even multi-TB) objects can be computationally intensive, and can lead to bottlenecks. In fact, some large S3 users have built special-purpose EC2 fleets solely to compute and validate checksums.

New Checksum Support
Today I am happy to tell you about S3’s new support for four checksum algorithms. It is now very easy for you to calculate and store checksums for data stored in Amazon S3 and to use the checksums to check the integrity of your upload and download requests. You can use this new feature to implement the digital preservation best practices and controls that are specific to your industry. In particular, you can specify the use of any one of four widely used checksum algorithms (SHA-1, SHA-256, CRC-32, and CRC-32C) when you upload each of your objects to S3.

Here are the principal aspects of this new feature:

Object Upload – The newest versions of the AWS SDKs compute the specified checksum as part of the upload, and include it in an HTTP trailer at the conclusion of the upload. You also have the option to supply a precomputed checksum. Either way, S3 will verify the checksum and accept the operation if the value in the request matches the one computed by S3. In combination with the use of HTTP trailers, this feature can greatly accelerate client-side integrity checking.

Multipart Object Upload – The AWS SDKs now take advantage of client-side parallelism and compute checksums for each part of a multipart upload. The checksums for all of the parts are themselves checksummed and this checksum-of-checksums is transmitted to S3 when the upload is finalized.

Checksum Storage & Persistence – The verified checksum, along with the specified algorithm, are stored as part of the object’s metadata. If Server-Side Encryption with KMS Keys is requested for the object, then the checksum is stored in encrypted form. The algorithm and the checksum stick to the object throughout its lifetime, even if it changes storage classes or is superseded by a newer version. They are also transferred as part of S3 Replication.

Checksum Retrieval – The new GetObjectAttributes function returns the checksum for the object and (if applicable) for each part.

Checksums in Action
You can access this feature from the AWS Command Line Interface (CLI), AWS SDKs, or the S3 Console. In the console, I enable the Additional Checksums option when I prepare to upload an object:

Then I choose a Checksum function:

If I have already computed the checksum I can enter it, otherwise the console will compute it.

After the upload is complete I can view the object’s properties to see the checksum:

The checksum function for each object is also listed in the S3 Inventory Report.

From my own code, the SDK can compute the checksum for me:

with open(file_path, 'rb') as file:
    r = s3.put_object(
        Bucket=bucket,
        Key=key,
        Body=file,
        ChecksumAlgorithm='sha1'
    )

Or I can compute the checksum myself and pass it to put_object:

with open(file_path, 'rb') as file:
    r = s3.put_object(
        Bucket=bucket,
        Key=key,
        Body=file,
        ChecksumSHA1='fUM9R+mPkIokxBJK7zU5QfeAHSy='
    )

When I retrieve the object, I specify checksum mode to indicate that I want the returned object validated:

r = s3.get_object(Bucket=bucket, Key=key, ChecksumMode='ENABLED')

The actual validation happens when I read the object from r['Body'], and an exception will be raised if there’s a mismatch.

Watch the Demo
Here’s a demo (first shown at re:Invent 2021) of this new feature in action:

Available Now
The four additional checksums are now available in all commercial AWS Regions and you can start using them today at no extra charge.

— Jeff;

Zabbix security advisories regarding CVE-2022-23131 and CVE-2022-23134

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/zabbix-security-advisories-regarding-cve-2022-23131-and-cve-2022-23134/19720/

Here at Zabbix, the security of our product is our top priority. It has come to our attention that two potential CVE issues have been highlighted in tech media outlets  –  CVE-2022-23131 and CVE-2022-23134.

The most critical issue – CVE-2022-23131, affects only Zabbix instances where SAML SSO authentication is in use. While CVE-2022-23134 Affects Zabbix 5.4.x releases older than Zabbix 5.4.9.

Zabbix is aware of the following vulnerabilities And they have since been fixed in Zabbix version 5.4.9 and the stable release of Zabbix 6.0 LTS.

  • CVE-2022-23131 – Unsafe client-side session storage leading to authentication bypass/instance takeover via Zabbix Frontend with configured SAML
    • Affected versions: 5.4.0 – 5.4.8; 6.0.0alpha1
  • CVE-2022-23134 – Possible view of the setup pages by unauthenticated users if config file already exists
    • Affected versions: 5.4.0 – 5.4.8; 6.0.0 – 6.0.0beta1

We urge everyone who is using the SAML SSO authentication features in your environment o update your Zabbix instance to one of the aforementioned versions where the security vulnerabilities have been resolved.

keep track of any potential Zabbix security issues, the affected versions, and the required updates, visit our public Zabbix Security Advisories and CVE database page.

The post Zabbix security advisories regarding CVE-2022-23131 and CVE-2022-23134 appeared first on Zabbix Blog.

Staying Secure in a Global Cyber Conflict

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/02/25/russia-ukraine-staying-secure-in-a-global-cyber-conflict/

Staying Secure in a Global Cyber Conflict

Now that Russia has begun its armed invasion of Ukraine, we should expect increasing risks of cybersecurity attacks and incidents, either as spillover from cyberattacks targeting Ukraine or direct attacks against actors supporting Ukraine.

Any state-sponsored Russian attacks aiming to support the Russian invasion of Ukraine, or to retaliate for US, NATO, or other foreign measures taken in response to the Russian invasion of Ukraine, are most likely to be destructive or disruptive in nature rather than aiming to steal data. This blog discusses the types of attacks organizations may see — including distributed denial of service (DDoS), website defacements, and the use of ransomware or destructive malware — and recommends steps for their mitigation or remediation.

As we have stated before, we do not believe organizations need to panic. But as per guidance from numerous governments, we do believe it is wise to be extra vigilant at this time. Rapid7 will continue to monitor the cybersecurity risks, both internally and for our Managed Detection and Response (MDR) customers as the situation evolves. We will post updates as relevant and suggest subscription to our blog to see them as they are posted.

Malware

One of the most concerning possibilities is the risk of a destructive malware attack on the US, NATO members, or other foreign countries. This could take the form of a direct attack or spillover from an attack on Ukraine, such as the 2017 NotPetya operation that targeted Ukraine and spread to other parts of the globe. Cybersecurity researchers have just discovered a new data wiping malware, dubbed HermeticWiper (AKA KillDisk.NCV), that infected hundreds of Ukrainian machines in the last two months. This seems to be a custom-written malware that corrupts the Master Boot Record (MBR), resulting in boot failure. This malware, like NotPetya, is intended to be destructive and will cripple the assets that it infects.

As always, the best malware prevention is to avoid infection in the first place — a risk we can minimize by ensuring that assets are up to date and use strong access controls, including multi-factor authentication. Additionally, it is crucial to have an incident response plan in place for the worst-case scenario, as well as a business continuity plan — including failover infrastructure if possible — for business-critical assets.

DDoS

There have already been reports of DDoS attacks on Ukrainian websites, and Russia has historically used DDoS in support of operations against other former Soviet republics, such as Georgia, in the past. Given this context, it is plausible that state-sponsored Russian actors would use DDoS if they choose to retaliate in response to measures taken against Russia for the invasion of Ukraine, such as sanctions or cyber operations from NATO countries.

While DDoS does not receive the same level of attention as some other forms of attack, it can still have significant impacts to business operations. DDoS mitigations can include reduction of attack surface area via Content Distribution Networks or load balancers, as well as the use of Access Control Lists and firewalls to drop traffic coming from attacker nodes.

Phishing campaigns

Russian state-sponsored actors are also well known for engaging in spear-phishing attacks, specifically with compromised valid accounts. Defenders should ensure strong spam filtering and attachment scanning is in place. Educating end users of the dangers of phishing and regularly running phishing campaigns will also help mitigate this issue.

State-sponsored, APT-style groups are not the only relevant threats. In times of crisis, it is common to see phishing attacks linking to malicious websites masquerading as news, aid groups, or other seemingly relevant content. Opportunistic scammers and other bad actors will attempt to take advantage of our human nature when curiosity, anxiety, and desire to help can make people less suspicious. Remain vigilant and avoid clicking unknown links or opening attachments — basic cyber hygiene that can be forgotten when emotions run high.

Brute-force attacks

According to a report from the NSA, CISA, FBI, and NCSC, “From mid-2019 through early 2021, Russian General Staff Main Intelligence Directorate (GRU) … conduct[ed] widespread, distributed, and anonymized brute-force access attempts against hundreds of government and private sector targets worldwide.” GRU used the discovered credentials to gain access into networks and further used known vulnerabilities such as CVE-2020-0688 and CVE-2020-17144 to increase access.

The best mitigation for these types of attacks is to enable MFA on all systems. Minimize externally facing systems and ensure externally facing systems are fully patched.

Defacement

Ukraine has also been experiencing website defacements, which provide attackers with an opportunity to spread messaging. Website defacement is typically associated with hacktivist activity, but state-sponsored Russian actors could pose as hacktivists in order to disguise Russian state involvement, and spread their strategic communication themes to international audiences by defacing Western websites.

Website defacement often occurs as a result of weak passwords for admin accounts, cross-site scripting, injection, file upload, or vulnerable plugins. This can be managed by limiting the level of access accounts have and enforcing strong passwords. Additionally, looking for places where scripts or iframes could be injected or where SQL injection could occur can help identify vulnerabilities to remediate.

Ransomware

Ransomware could also be used to disrupt foreign targets. Criminals based in Russia were believed to be behind the 2021 ransomware attack on Colonial Pipeline in the United States. Ransomware can have disruptive effects on targets, and the attackers could simply refrain from decrypting files, even if they receive ransom payments, in order to maximize and extend the disruptive impact on victims. Additionally, opportunistic attackers who are actually looking for ransoms will still be on the prowl, and are likely to take advantage of the chaos.

To this end, defenders should:

  • Evaluate asset and application configurations to ensure resilience
  • Double-check visibility into the functioning of business-critical assets
  • Assess incident response processes in the case of an incident

What else should you be doing?

The following activities are mission-critical in times of uncertainty, but they are also best practices in general.

  • Continuous monitoring: Reinforce cybersecurity measures and staff during nights, weekends, and holidays. Threat actors are known to target their victims when there are gaps in “eyes on glass.”
  • Incident response plan: Prepare a dedicated team with a detailed workflow and a contact person that will be available offline in case of a cybersecurity incident.
  • Back up data: Implement data backup procedures of the company networks and systems. Backup procedures should be conducted on a frequent, regular basis for immediate recovery. Also, be sure to store backups offline and check them regularly to ensure they have not been poisoned with malware.
  • Reduce opportunities for attackers: Identify exposures, vulnerabilities, and misconfigurations that can provide opportunities for attackers to gain a foothold in your environment, and apply relevant mitigations or patches. In particular, Russian operators are well known to exploit edge systems. The Cybersecurity and Infrastructure Security Agency (CISA) recently put out an alert listing 13 known vulnerabilities that Russian state-sponsored threat actors use to initially compromise networks. We recommend this as a starting point for focused patching and mitigation.
  • Stay informed: Follow the latest updates and recommendations provided by Rapid7, as well as governmental security entities in specific press releases/alerts from the Ukraine CERT, The Security Service of Ukraine (SSU), and the US CISA.

We expect the situation to be fluid over the coming days and weeks, and security guidance and threats may also evolve as the conflict develops. The measures suggested in this blog will continue to be relevant, and we plan to provide additional information as needed.

In the meantime, you can also check this blog to see how Rapid7 can help you prepare for and respond to cyber attacks. We also recommend organizations check their government’s cybersecurity website for guidance.

Zabbix 6.0 LTS is out now!

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/zabbix-6-0-lts-is-out-now/18757/

The Zabbix team is proud to announce the release of Zabbix 6.0 LTS. The latest version comes packed with many new features, improvements, new templates and integrations.

New features

  • Out-of-the-box High Availability cluster for Zabbix server with support for one or multiple standby nodes
  • Redesigned Services section, tailored for flexible Business Service monitoring with the ability to monitor over 100k services, define flexible service calculation rules, perform root cause analysis, receive service status change alerts, and more
  • New machine learning trend functions for baseline monitoring and anomaly detection
  • Monitor your Kubernetes instance with out-of-the-box Kubernetes monitoring for pods, nodes, and Kubernetes component monitoring
  • New Audit log schema enables detailed logging for both the Zabbix frontend and backend
  • Track your host status and location with the new Geomap widget
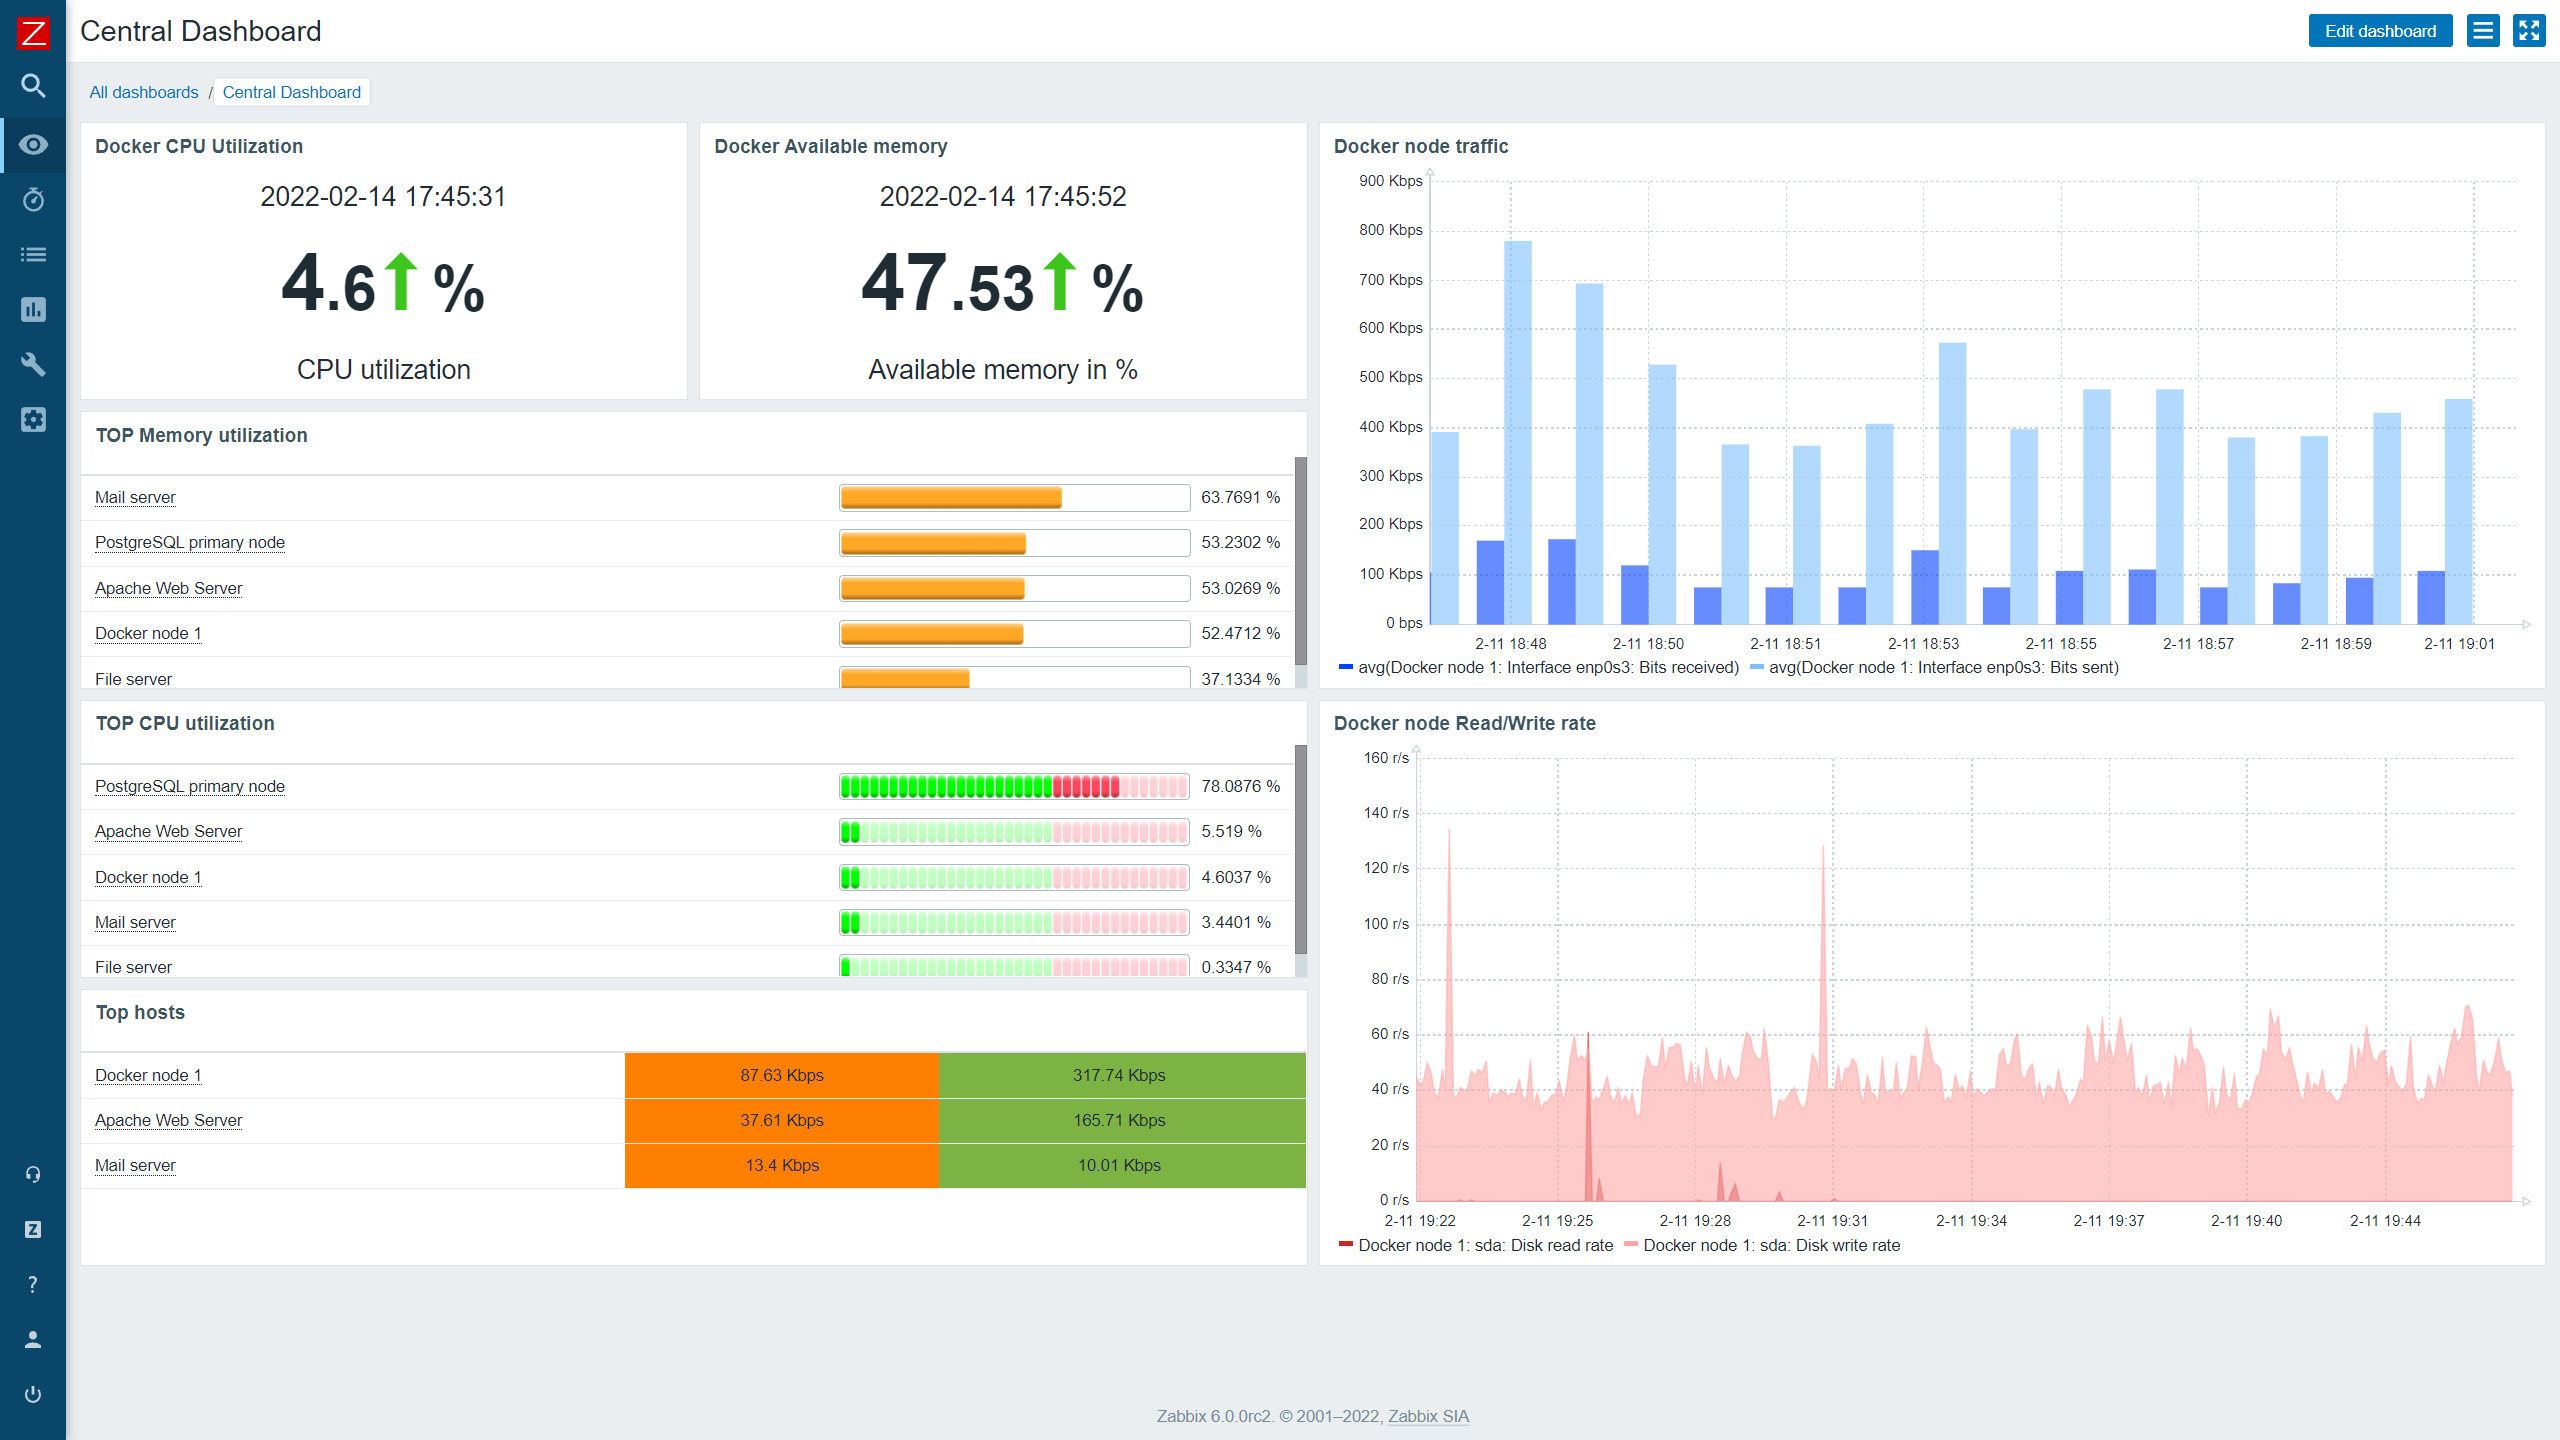
  • The Top hosts widget provides Top N and Bottom N host views sorted by item values
  • Ability to define custom Zabbix password complexity requirements
  • Multiple UI improvements. Hosts can now be created directly from the Monitoring section.
  • Zabbix Agent2 now supports loading stand-alone plugins without having to recompile the Agent2
  • Monitor SSL/TLS certificates with a new Zabbix Agent2 item
  • Performance improvements for Zabbix Server, Proxy, and Frontend
  • All of the official Zabbix templates are now stand-alone and do not require importing additional template dependencies

  • And many other improvements and features


This version also provides a set of new templates for the following vendors:

  • F5 BIG-IP

  • Cisco ASAv

  • HPE ProLiant servers

  • Cloudflare

  • InfluxDB

  • Travis CI

  • Dell PowerEdge

  • pfSense

  • Kubernetes

  • Mikrotik

  • Nginx Plus

  • VMware SD-WAN VeloCloud

  • GridGain

  • Systemd

  • As well as a new Github webhook integration

The latest LTS release will receive full official support for 3 years and limited support, which consists of bug fixes for 5 years.

Find out more about Zabbix 6.0 LTS by visiting our What’s new in Zabbix 6.0 LTS webinar, covering the most important new features and improvements: https://www.zabbix.com/webinars

An overview of the new features and changes can be found on our What’s new in Zabbix 6.0 page:

https://www.zabbix.com/whats_new_6_0

What’s new in Zabbix 6.0.0 documentation section:

https://www.zabbix.com/documentation/current/en/manual/introduction/whatsnew600

Take a look at the release notes to see the full list of new features and improvements:

https://www.zabbix.com/rn/rn6.0.0

Zabbix 6.0 LTS packages

The official Zabbix packages are available for:

  • Linux distributions for different hardware platforms on RHEL, CentOS, Oracle Linux, Debian, SuSE, Ubuntu, Raspbian
  • Virtualization platforms based on VMWare, VirtualBox, Hyper-V, XEN
  • Docker
  • Packages and pre-compiled agents for most popular platforms, including macOS and MSI packages for Windows

You can find the download instructions and download the new version on the download page: https://www.zabbix.com/download

One-click deployment is available for the following cloud platforms:

  • AWS, Azure, Google Cloud, Digital Ocean, Linode, Oracle Cloud, Red Hat OpenShift, Yandex Cloud

Zabbix 6.0 also incorporates the features added in Zabbix 5.2 and Zabbix 5.4 non-LTS versions.

Upgrading to Zabbix 6.0 LTS

In order to upgrade to Zabbix 6.0 LTS, you need to upgrade your repository package and download and install the new Zabbix component packages (Zabbix server, proxy, frontend, and other Zabbix components). When you start the Zabbix Server, an automatic database schema upgrade will be performed. Zabbix Agents are backward compatible; therefore, it is not required to install the new agent versions. You can do it at a later time if needed.

If you’re using the official Docker container images – simply deploy a new set of containers for your Zabbix components. Once the Zabbix server container connects to the backend database, the database upgrade will be performed automatically.

You can find step-by-step instructions for the upgrade process to Zabbix 6.0 LTS in the Zabbix documentation.

If you’re interested in a list of changes and an additional pre-upgrade checklist – the following blog post covers the nuances of the upgrade process and takes a look under the hood at what changes are performed during the upgrade.

The post Zabbix 6.0 LTS is out now! appeared first on Zabbix Blog.

Amazon Elastic File System Update – Sub-Millisecond Read Latency

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/amazon-elastic-file-system-update-sub-millisecond-read-latency/

Amazon Elastic File System (Amazon EFS) was announced in early 2015 and became generally available in 2016. We launched EFS in order to make it easier for you to build applications that need shared access to file data. EFS is (and always has been) simple and serverless: you simply create a file system, attach it to any number of EC2 instances, Lambda functions, or containers, and go about your work. EFS is highly durable and scalable, and gives you a strong read-after-write consistency model.

Since the 2016 launch we have added many new features and capabilities including encryption data at rest and in transit, an Infrequent Access storage class, and several other lower cost storage classes. We have also worked to improve performance, delivering a 400% increase in read operations per second, a 100% increase in per-client throughput, and then a further tripling of read throughput.

Our customers use EFS file systems to support many different applications and use cases including home directories, build farms, content management (WordPress and Drupal), DevOps (Git, GitLab, Jenkins, and Artifactory), and machine learning inference, to name a few of each.

Sub-Millisecond Read Latency
Faster is always better, and today I am thrilled to be able to tell you that your latency-sensitive EFS workloads can now run about twice as fast as before!

Up until today, EFS latency for read operations (both data and metadata) was typically in the low single-digit milliseconds. Effective today, new and existing EFS file systems now provide average latency as low as 600 microseconds for the majority of read operations on data and metadata.

This performance boost applies to One Zone and Standard General Purpose EFS file systems. New or old, you will still get the same availability, durability, scalability, and strong read-after-write consistency that you have come to expect from EFS, at no additional cost and with no configuration changes.

We “flipped the switch” and enabled this performance boost for all existing EFS General Purpose mode file systems over the course of the last few weeks, so you may already have noticed the improvement. Of course, any new file systems that you create will also benefit.

Learn More
To learn more about the performance characteristics of EFS, read Amazon EFS Performance.

— Jeff;

PS – Our multi-year roadmap contains a bunch of short-term and long-term performance enhancements, so stay tuned for more good news!

New – Amazon EC2 C6a Instances Powered By 3rd Gen AMD EPYC Processors for Compute-Intensive Workloads

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c6a-instances-powered-by-3rd-gen-amd-epyc-processors-for-compute-intensive-workloads/

At AWS re:Invent 2021, we launched Amazon EC2 M6a instances powered by the 3rd Gen AMD EPYC processors, running at frequencies up to 3.6 GHz, which offer customers up to 35 percent improvement in price-performance compared to M5a instances.

Many customers are looking for ways to optimize their cloud utilization, and they are taking advantage of the compute choice that Amazon EC2 offers. Customers such as Dropbox, Capital One, and Sprinklr have been able to realize the cost benefits of AWS using EC2 instances powered by AMD EPYC processors.

Today, I am happy to announce the availability of the new compute-optimized Amazon EC2 C6a instances, which offer up to up to 15 percent improvement in price-performance versus C5a instances, and 10 percent lower cost than comparable x86-based EC2 instances.

These instances are ideal for running compute-intensive workloads such as high-performance web servers, batch processing, ad serving, machine learning, multi-player gaming, video encoding, high performance computing (HPC) such as scientific modeling, and machine learning.

Compared to C5a instances, this new instance type provides:

To increase instance security, C6a instances have always-on memory encryption with AMD Transparent Single Key Memory Encryption (TSME), and support new AVX2 instructions for accelerating encryption and decryption algorithms.

Like M6a, C6a instances are also available in 10 sizes:

Name vCPUs Memory
(GiB)
Network Bandwidth
(Gbps)
EBS Throughput
(Gbps)
c6a.large 2 4 Up to 12.5 Up to 6.6
c6a.xlarge 4 8 Up to 12.5 Up to 6.6
c6a.2xlarge 8 16 Up to 12.5 Up to 6.6
c6a.4xlarge 16 32 Up to 12.5 Up to 6.6
c6a.8xlarge 32 64 12.5 6.6
c6a.12xlarge 48 96 18.75 10
c6a.16xlarge 64 128 25 13.3
c6a.24xlarge 96 192 37.5 20
c6a.32xlarge 128 256 50 26.6
c6a.48xlarge 192 384 50 40

The new instances are built on the AWS Nitro System, a collection of building blocks that offloads many of the traditional virtualization functions to dedicated hardware for high performance, high availability, and highly secure cloud instances.

Available Now
C6a instances are available today in three AWS Regions: US East (N. Virginia), US West (Oregon), and EU (Ireland). As usual with EC2, you pay for what you use. For more information, see the EC2 pricing page.

To learn more, visit the EC2 C6a instance and AWS/AMD partner page. You can send feedback to  [email protected], AWS re:Post for EC2, or through your usual AWS Support contacts.

— Channy

New for App Runner – VPC Support

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-for-app-runner-vpc-support/

With AWS App Runner, you can quickly deploy web applications and APIs at any scale. You can start with your source code or a container image, and App Runner will fully manage all infrastructure including servers, networking, and load balancing for your application. If you want, App Runner can also configure a deployment pipeline for you.

Starting today, App Runner enables your services to communicate with databases and other applications hosted in an Amazon Virtual Private Cloud (VPC). For example, you can now connect App Runner services to databases in Amazon Relational Database Service (RDS), Redis or Memcached caches in Amazon ElastiCache, or your own applications running in Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (EKS), Amazon Elastic Compute Cloud (Amazon EC2), or on-premises and connected via AWS Direct Connect.

Previously, in order for your App Runner application to connect to these resources, they needed to be publicly accessible over the internet. With this feature, App Runner applications can connect to private endpoints in your VPC, and you can enable a more secure and compliant environment by removing public access to these resources.

Within App Runner, you can now create VPC connectors that specify which VPC, subnets, and security groups to use for private networking. Once configured, you can use a VPC connector with one or more App Runner services.

When connected to a VPC, all outbound traffic from your AppRunner service will be routed based on the VPC routing rules. Services will not have access to the public internet (including AWS APIs) unless allowed by a route to a NAT Gateway. You can also set up VPC endpoints to connect to AWS APIs such as Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB to avoid NAT traffic.

The VPC connectors in App Runner work similarly to VPC networking in AWS Lambda and are based on AWS Hyperplane, the internal Amazon network function virtualization system behind AWS services and resources like Network Load Balancer, NAT Gateway, and AWS PrivateLink.

Let’s see how this works in practice with a web application connected to an RDS database.

Preparing the Amazon RDS Database
I start by configuring a database for my application. To simplify capacity management for this database, I use Amazon Aurora Serverless. In the RDS console, I create an Amazon Aurora MySQL-Compatible database. For the Capacity type, I choose Serverless. For networking, I use my default VPC and the default security group. I don’t need to make the database publicly accessible because I am going to connect using private VPC networking. To simplify connecting later, I enable AWS Identity and Access Management (IAM) database authentication.

I start an Amazon Linux EC2 instance in the same VPC. To connect from the EC2 instance to the database, I need a MySQL client. I install MariaDB, a community-developed branch of MySQL:

sudo yum install mariadb

Then, I connect to the database using the admin user.

mysql -h <DATABASE_HOST> -u admin -P

I enter the admin user password to log in. Then, I create a new user (bookuser) that is configured to use IAM authentication.

CREATE USER bookuser IDENTIFIED WITH AWSAuthenticationPlugin AS 'RDS'; 

I create the bookcase database and give permissions to the bookuser user to query the bookcase database.

CREATE DATABASE bookcase;
GRANT SELECT ON bookcase.* TO 'bookuser'@'%’;

To store information about some of my books, I create the authors and books tables.

CREATE TABLE authors (
  authorId INT,
  name varchar(255)
 );

CREATE TABLE books (
  bookId INT,
  authorId INT,
  title varchar(255),
  year INT
);

Then, I insert some values in the two tables:

INSERT INTO authors VALUES (1, "Issac Asimov");
INSERT INTO authors VALUES (2, "Robert A. Heinlein");
INSERT INTO books VALUES (1, 1, "Foundation", 1951);
INSERT INTO books VALUES (2, 1, "Foundation and Empire", 1952);
INSERT INTO books VALUES (3, 1, "Second Foundation", 1953);
INSERT INTO books VALUES (4, 2, "Stranger in a Strange Land", 1961);

Preparing the Application Source Code Repository
With App Runner, I can deploy a new service from code hosted in a source code repository or using a container image. In this example, I use a private project that I have on GitHub.

It’s a very simple Python web application connecting to the database I just created. This is the source code of the app (server.py):

from wsgiref.simple_server import make_server
from pyramid.config import Configurator
from pyramid.response import Response
import os
import boto3
import mysql.connector

import os

DATABASE_REGION = 'us-east-1'
DATABASE_CERT = 'cert/us-east-1-bundle.pem'
DATABASE_HOST = os.environ['DATABASE_HOST']
DATABASE_PORT = os.environ['DATABASE_PORT']
DATABASE_USER = os.environ['DATABASE_USER']
DATABASE_NAME = os.environ['DATABASE_NAME']

os.environ['LIBMYSQL_ENABLE_CLEARTEXT_PLUGIN'] = '1'

PORT = int(os.environ.get('PORT'))

rds = boto3.client('rds')

try:
    token = rds.generate_db_auth_token(
        DBHostname=DATABASE_HOST,
        Port=DATABASE_PORT,
        DBUsername=DATABASE_USER,
        Region=DATABASE_REGION
    )
    mydb =  mysql.connector.connect(
        host=DATABASE_HOST,
        user=DATABASE_USER,
        passwd=token,
        port=DATABASE_PORT,
        database=DATABASE_NAME,
        ssl_ca=DATABASE_CERT
    )
except Exception as e:
    print('Database connection failed due to {}'.format(e))          

def all_books(request):
    mycursor = mydb.cursor()
    mycursor.execute('SELECT name, title, year FROM authors, books WHERE authors.authorId = books.authorId ORDER BY year')
    title = 'Books'
    message = '<html><head><title>' + title + '</title></head><body>'
    message += '<h1>' + title + '</h1>'
    message += '<ul>'
    for (name, title, year) in mycursor:
        message += '<li>' + name + ' - ' + title + ' (' + str(year) + ')</li>'
    message += '</ul>'
    message += '</body></html>'
    return Response(message)

if __name__ == '__main__':

    with Configurator() as config:
        config.add_route('all_books', '/')
        config.add_view(all_books, route_name='all_books')
        app = config.make_wsgi_app()
    server = make_server('0.0.0.0', PORT, app)
    server.serve_forever()

The application uses the AWS SDK for Python (boto3) for IAM database authentication, the Pyramid web framework, and the MySQL connector for Python. The requirements.txt file describes the application dependencies:

boto3
pyramid==2.0
mysql-connector-python

To use SSL/TLS encryption when connecting to the database, I download a certificate bundle and add it to my source code repository.

Using VPC Support in AWS App Runner
In the App Runner console, I select Source code repository and the branch to use.

Console screenshot.

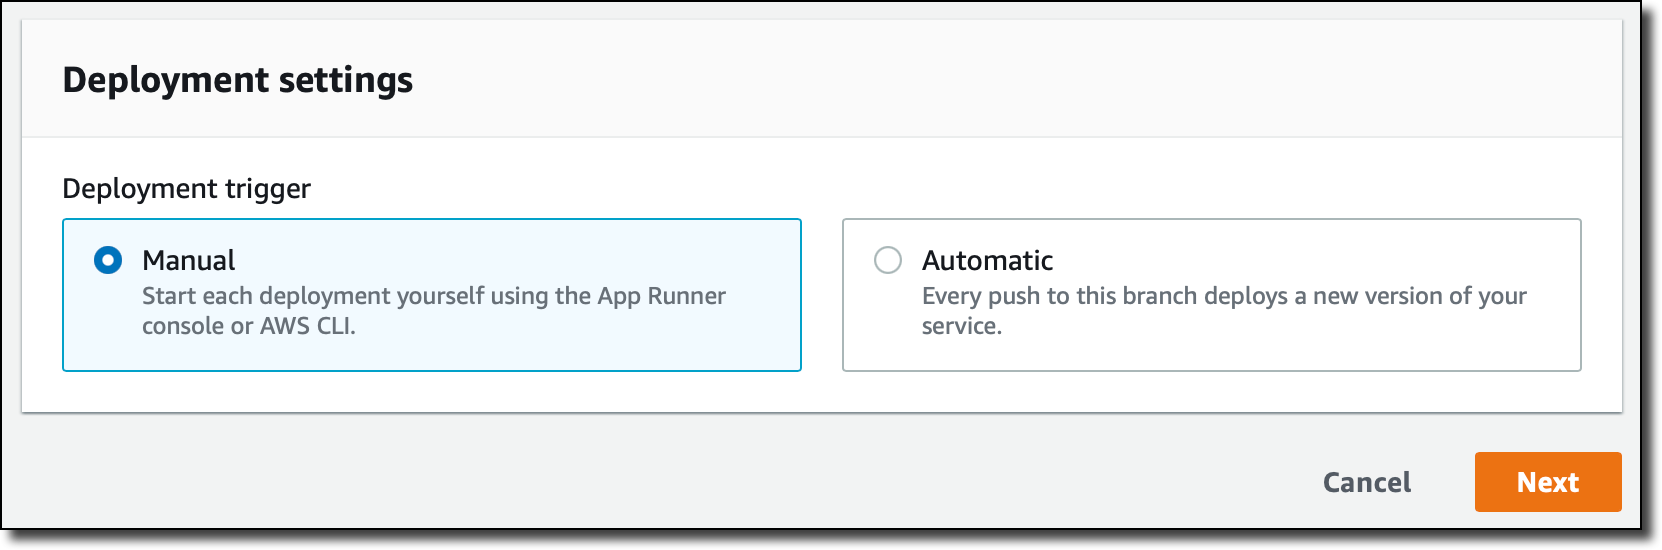
For the deployment settings, I choose Manual. Optionally, I could have selected the Automatic deployment trigger to have every push to this branch deploy a new version of my service.

Console screenshot.

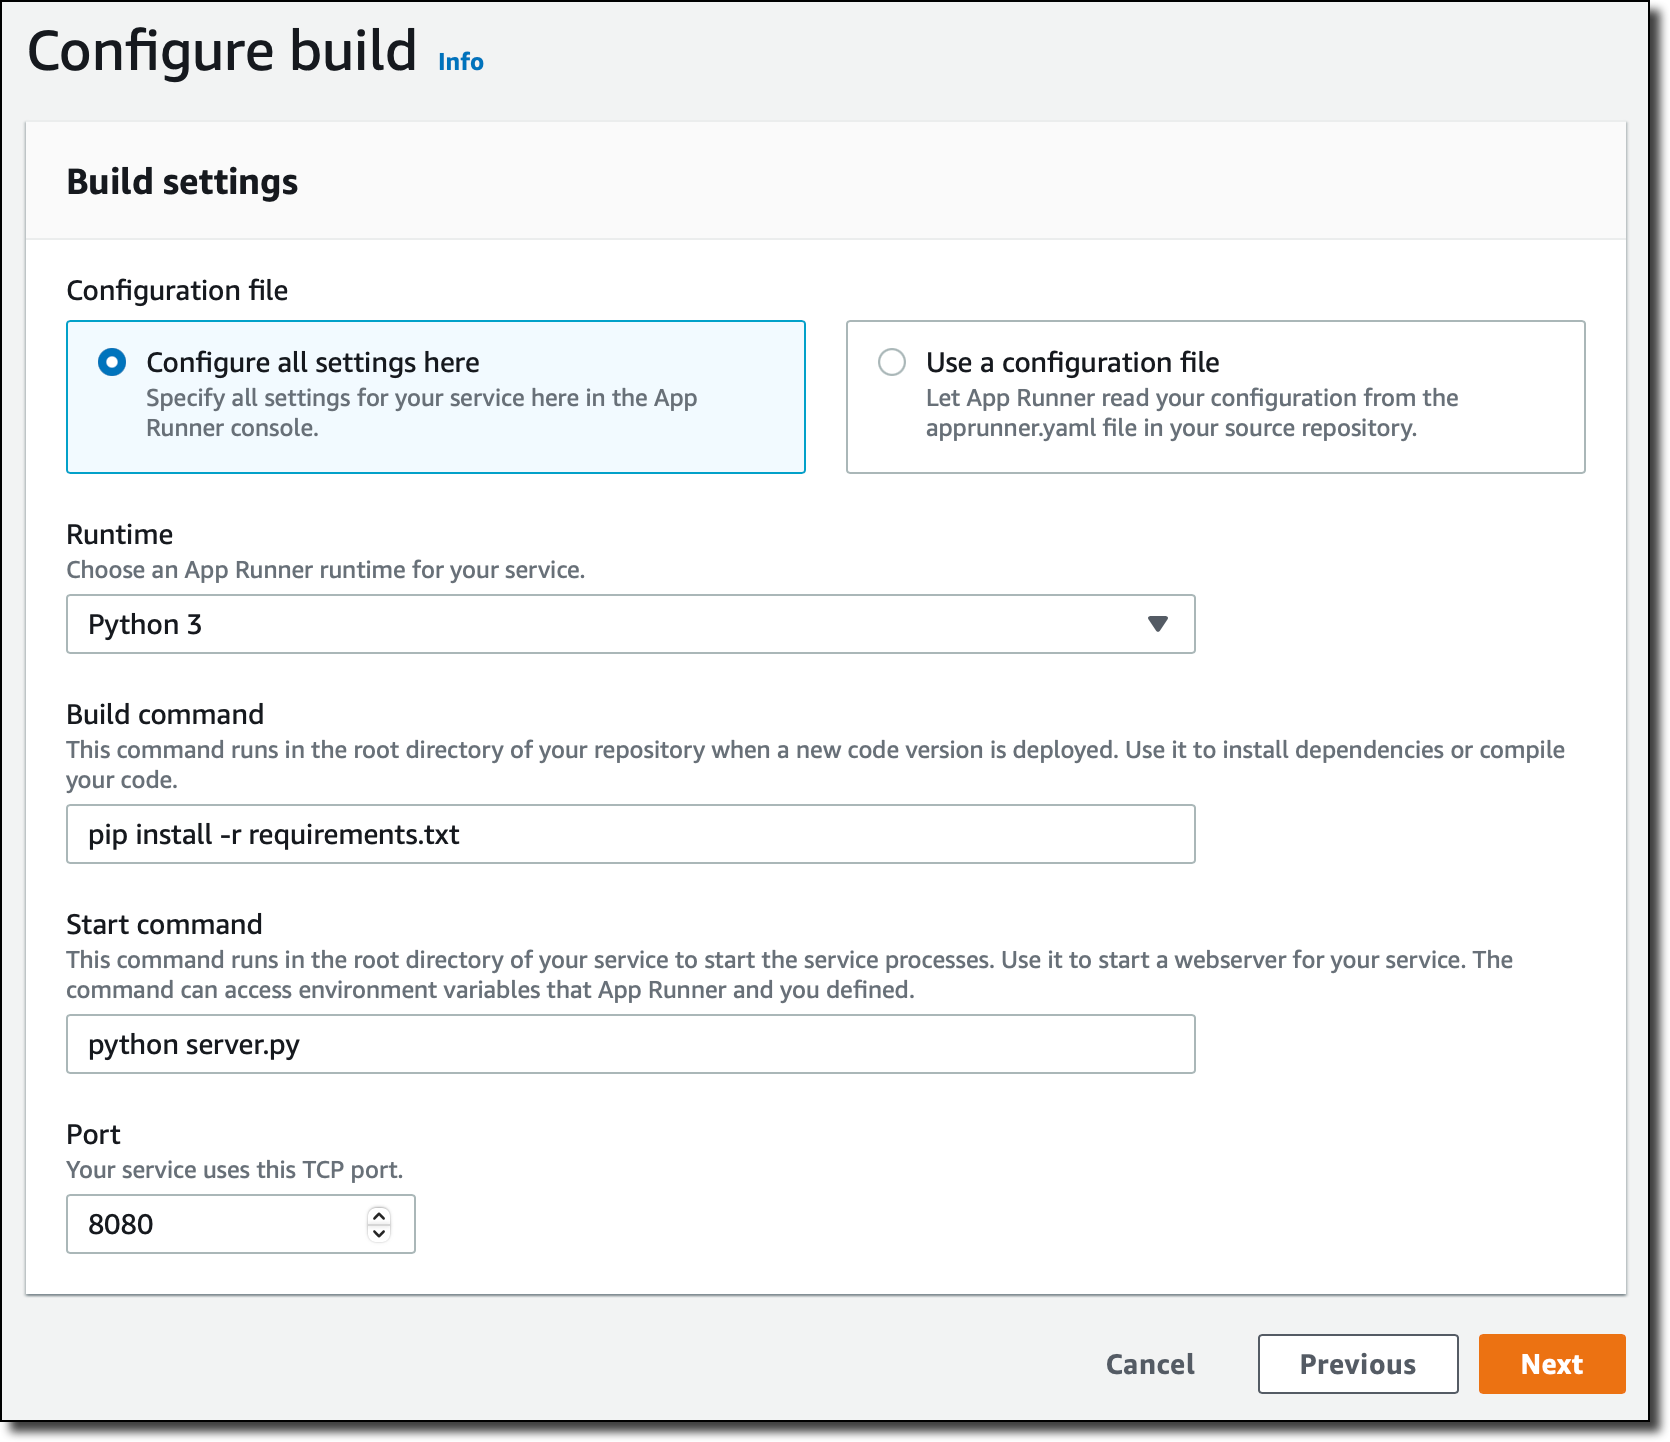
Then, I configure the build. This is a very simple application, so I pass the build and start commands in the console:

Build command – pip install -r requirements.txt
Start command – python server.py

For more advanced use cases, I would add an apprunner.yaml configuration file to my repository as in this sample application.

Console screenshot.

In the service configuration, I add the environment variables used by the application to connect to the database. I don’t need to pass a database password here because I am using IAM authentication.

Console screenshot.

In the Security section, I select an IAM role that gives permissions to connect to the database using IAM database authentication as described in Creating and using an IAM policy for IAM database access.

Console screenshot.

Here’s the syntax of the IAM role. I find the database Resource ID in the Configuration tab of the RDS console.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "rds-db:connect"
            ],
            "Resource": [
                "arn:aws:rds-db:<REGION>:<ACCOUNT>:dbuser:<DB_RESOURCE_ID>/<DB_USER>"
            ]
        }
    ]
}

For the role trust policy,   I follow the instruction for instance roles in How App Runner works with IAM.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "Service": "tasks.apprunner.amazonaws.com"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}

For Networking, I select the new option to use a Custom VPC for outgoing network traffic and then add a new VPC connector.

Console screenshot.

To add a new VPC connector, I write down a name and then select the VPC, subnets, and security groups to use. Here, I select all the subnets of my default VPC and the default security group. In this way, the App Runner service will be able to connect to the RDS database.

Console screenshot.

The next time, when configuring another application with the same VPC networking requirements, I can just select the VPC connector I created before.

Console screenshot. I review all the settings and then create and deploy the service.

After a few minutes, the service is running, and I choose the default domain to open a new tab in my browser. The application is connected to the database using VPC networking and performs a SQL query to join the books and authors tables and provide some reading suggestions. It works!

Browser screenshot.

Availability and Pricing
VPC connectors are available in all AWS Regions where AWS App Runner is offered. For more information, see the Regional Services List. There is no additional cost for using this feature, but you pay the standard pricing for data transmission or any NAT gateway or VPC endpoints you set up. You can set up VPC connectors with the AWS Management Console, AWS Command Line Interface (CLI), AWS SDKs, and AWS CloudFormation.

With VPC connectors, you can deploy your applications using App Runner and connect them to your private databases, caches, and applications running in a VPC or on-premises and connected via AWS Direct Connect.

Build and run web applications at any scale and connect to your private VPC resources with AWS App Runner.

— Danilo
Demonstrate your AWS Cloud Storage knowledge and skills with new digital badges!

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/demonstrate-your-aws-cloud-storage-knowledge-and-skills-with-new-digital-badges/

Are you a cloud storage professional or an on-premises storage pro who’s curious about cloud storage? Are you interested in demonstrating your AWS Storage knowledge and skills with potential employers and your community of peers? If so, I’d like to bring to your attention the recent launch of digital badges aligned to Learning Plans for Block Storage and Object Storage on AWS Skill Builder. In this 2021 blog post by Indeed, cloud-computing is the number one in-demand skill employers are looking for.

The new, verifiable, digital badges are available to everyone who scores at least 80 percent in the assessments associated with Learning Plans. The badges prove your knowledge and skills for Object Storage and/or Block Storage in the AWS Cloud. Badges, distributed and managed through Credly, carry with them metadata that enables verification of the issuer and the credential and lists the skills and knowledge demonstrated by the holder. Sharing badges on your résumé, peer community, and via social media assists in developing your career in cloud computing and celebrates your achievements. Some of you may be familiar with AWS re:Post, which launched during re:Invent 2021—your badges can be showcased in your AWS re:Post user profile too.

Object and Block Storage digital badges

AWS Skill Builder Learning Plans and digital badges for Block and Object Storage
Digital badges are available today for the Block Storage and Object Storage Learning Plans on AWS Skill Builder. Block Storage has a focus on Amazon Elastic Block Store (EBS), while Object Storage is focused on Amazon Simple Storage Service (Amazon S3). Both plans contain free learning content to help you build your knowledge in each of these areas and get ready for the assessments.

AWS Skill Builder offers a range of Learning Plans related to cloud computing skills. Learning Plans correspond to roles (architect, developer, etc.) and domain (databases, storage, etc.); each one is specifically designed to build your knowledge with a clear set of outcomes for you to achieve. Freely available, the Learning Plans and related assessments can be taken anywhere, anytime, providing equal and fair learning for all.

Badge assessments are linked to curriculum standards and are developed by service teams, field subject matter experts (SMEs), and content/curriculum SMEs. Therefore, employers can feel satisfied that the badges attained by a potential employee were awarded due to actual demonstrated skills and knowledge for Block and/or Object Storage. By the way, if you feel you have existing skills and knowledge and would prefer to skip straight to the assessment, you can. If you don’t pass, you’ll be guided to fill in your knowledge gaps, and you can then retake the assessment after 24 hours. To earn a badge, you need to score a minimum of 80 percent in the assessment.

The Block Storage and Object Storage Learning Plans are designed for you to take on your own, and you can track your own progress, making it easier to learn in your own time and manage your own learning development. They’re a great opportunity to refresh your skills, check your skills, or learn new ones.

Start collecting digital storage learning badges today
The Learning Plans and new digital badges for Block Storage and Object Storage help you showcase your in-demand knowledge and skills related to AWS Storage. As I mentioned earlier, enrollment for Learning Plans, and the subsequent assessments, are free for everyone. Find out more, and get started, at https://aws.amazon.com/training/badges. And be sure to share your accomplishment by posting on social media with the hashtag #AWSTraining and show off your badges!

— Steve

Making the web better. With blocks!

Post Syndicated from Joel Spolsky original https://www.joelonsoftware.com/2022/01/27/making-the-web-better-with-blocks/

You’ve probably seen web editors based on the idea of blocks. I’m typing this in WordPress, which has a little + button that brings up a long list of potential blocks that you can insert into this page:

This kind of “insert block” user interface concept is showing up in almost every blogging tool, web editor, note-taking app, and content management system. People like it and it makes sense.

We have seem to have standardized on one thing: the / key to insert a new block. Everything else, though, is completely proprietary and non-standard.

I thought, wouldn’t it be cool if blocks were interchangeable and reusable across the web?

Until now, every app that wants blocks has to implement them from scratch. Want a calendar block? Some kind of fancy Kanban board? Something to embed image galleries? Code it up yourself, buddy.

As a result of the non-standardization of blocks, our end-users suffer. If someone is using my blog engine, they can only use those blocks that I had time to implement. Those blocks may be pretty basic or incomplete. Users might want to use a fancier block that they saw in WordPress or Medium or Notion, but my editor doesn’t have it. Blocks can’t be shared or moved around very easily, and our users are limited to the features and capabilities that we had time to re-implement.

To fix this, we’re going to create a protocol called the Block Protocol.

It’s open, free, non-proprietary, we want it to be everywhere on the web.

It’s just a protocol that embedding applications can use to embed blocks. Any block can be used in any embedding application if they all follow the protocol.

Our hope is that this will make life much easier for app developers to support a huge variety of block types. At the same time, anyone can develop a block once and have it work in any blog platform, note-taking app, or content management system. It is all 100% free, open, and any sample code we develop showing how to use the protocol will be open-source.

We’ve released a very early draft of the Block Protocol, and we’ve started building some very simple blocks and a simple editor that can host them.

We’re hoping to foster an open source community that creates a huge open source library of amazing blocks:

What can be a block?

  • Anything that makes sense in a document: a paragraph, list, table, diagram, or a kanban board.
  • Anything that makes sense on the web: an order form, a calendar, a video.
  • Anything that lets you interact with structured or typed data: I’ll get to that in a minute.

If you work on any kind of editor—be it a blogging tool, a note-taking app, a content management system, or anything like that—you should allow your users to embed blocks that conform to the Block Protocol. This way you can write the embedding code once and immediately make your editor able to embed a rich variety of block types with no extra work on your part.

If you work on any kind of custom data type that might make sense to embed in web pages, you should support the Block Protocol. That way anybody with a hosting application that supports the protocol can embed your custom data type.

Because it’s all 100% open, we hope that the Block Protocol will become a web standard and commonly used across the Internet.

That will mean that common block types, from paragraphs and lists to images and videos, will get better and better. But it will also mean that some esoteric block types will be embeddable anywhere. Want to create a block that shows the Great Circle routing for a flight between two airports? Write the code for the block once and it can be embedded anywhere.

Oh, and one more thing. Blocks can be highly structured, that is, they can have types. That means that they magically become machine-readable without screen scraping. For example, if you want to create an event block to represent an event on a calendar, you will be able to specify a schema that describes the event data type in a standard way. That way tools like calendars can instantly parse and understand web pages that contain your event block, reliably.

Over time, it will mean that anyone can easy publish complex, typed data sets on the web that are automatically machine-readable without extra work. (Have you ever seen one of those websites where there’s a link to “download the data set in .XLS format”? Yeah, say goodbye to that.)

We’re going public with this very early in the development process because we need a lot of help!

Everything we have so far is version 0.1. It’s simple and not very good yet and going to need some iteration before it has the hope of truly being a useful web protocol.

This is an open protocol, free and non-proprietary, and it’s going to make the open web much better if widely adopted, so we need to start getting people involved early, giving us feedback, and building new things!

Go read more about the Block Protocol now!

New – Amazon EC2 X2iezn Instances Powered by the Fastest Intel Xeon Scalable CPU for Memory-Intensive Workloads

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-x2iezn-instances-powered-by-the-fastest-intel-xeon-scalable-cpu-for-memory-intensive-workloads/

Electronic Design Automation (EDA) workloads require high computing performance and a large memory footprint. These workloads are sensitive to faster CPU performance and higher clock speeds since the faster performance allows more jobs to be completed on the lower number of cores. At AWS re:Invent 2020, we launched Amazon EC2 M5zn instances which use second-generation Intel Xeon Scalable (Cascade Lake) processors with an all-core turbo clock frequency of up to 4.5 GHz, which is the fastest of any cloud instance.

Our customers have enjoyed the high single-threaded performance, high-speed networking, and balanced memory-to-vCPU ratio of EC2 M5zn instances. They have asked for instances that will leverage these features while also providing them a greater memory footprint per vCPU.

Today, we are launching Amazon EC2 X2iezn instances, which use the same Intel Xeon Scalable processors as M5zn instances, with an all-core turbo clock frequency of 4.5 GHz and up to 1.5 TiB of memory, which is the fastest of any cloud instance for EDA workloads. These instances are capable of delivering up to 55 percent better price-performance per vCPU compared to X1e instances.

X2iezn instances offer 32 GiB of memory per vCPU and will support up to 48 vCPUs and 1536 GiB of memory. Built on the AWS Nitro, they deliver up to 100 Gbps of networking bandwidth and 19 Gbps of dedicated Amazon EBS bandwidth to improve performance for EDA applications.

You might have noticed that we’re now using the “i” suffix in the instance type to specify that the instances are using an Intel processor, “e” in the memory-optimized instance family to indicate extended memory, “z” which indicates high-frequency processors, and “n” to support higher network bandwidth up to 100 Gbps.

X2iezn instances are VPC only, HVM-only, and EBS-Optimized, with support for Optimize vCPU. As you can see, the memory-to-vCPU ratio on these instances is the same as that of previous-generation X1e instances:

Instance Name vCPUs RAM (GiB) Network Bandwidth (Gbps) EBS-Optimized Bandwidth (Gbps)
x2iezn.2xlarge 8 256 Up to 25 3.170
x2iezn.4xlarge 16 512 Up to 25 4.750
x2iezn.6xlarge 24 768 50 9.5
x2iezn.8xlarge 32 1024 75 12
x2iezn.12xlarge 48 1536 100 19
x2iezn.metal 48 1536 100 19

Many customers will be able to benefit from using X2iezn instances to improve performance and efficiency for their EDA workloads. Here are some examples:

  • Annapurna Labs tested the X2iezn instances with Calibre’s Design Rule Checking, which has shown a 40 percent faster runtime compared to X1e instances, and a 25 percent faster runtime over R5d instances.
  • Astera Labs is a fabless, cloud-based semiconductor company developing purpose-built CXL, PCIe, and Ethernet connectivity solutions for data-centric systems. They were able to see performance gains of up to 25 percent compared to similar EDA workloads running on R5 instances.
  • Cadence tested the X2iezn instances using their Pegasus True Cloud feature, which allows designers to run physical verification jobs on the cloud and observed a 50 percent performance improvement over R5 instances. They see X2iezn instances as an excellent environment for testing EDA workloads.
  • NXP Semiconductors worked with AWS to run their Calibre and Spectre workloads on Amazon EC2 X2iezn instances, which measured 10-15 percent higher performance using X2iezn instances compared to their on-premises, Xeon Gold 6254 with max turbo frequency of 4.0GHz.
  • Siemens EDA worked with AWS to test the new Amazon EC2 X2iezn HPC/EDA focused instances with the industry performance and sign-off leader Calibre evaluating advanced node DRC workloads. They were pleased to demonstrate performance improvements of up to 14% using the 4.5 GHz all core turbo frequency of X2iezn instances for all VMs in the run. Additionally, they successfully demonstrated the use of a heterogeneous server configuration using the X2iezn as the primary node and other lower memory VMs for remote compute – providing an 11% speed up and attractive value. These results confirmed the X2iezn is a good fit for primary server EDA workloads for Calibre Physical and Circuit verification applications.
  • Synopsys IC Validator provides highly scalable high-performance physical verification signoff. They achieved 15 percent performance improvement, scalability to 1000s of cores, and 30 percent better efficiency using IC Validator’s unique elastic CPU management technology versus R5d instances.

Things to Know
Here are some fun facts about the X2iezn instances:

Optimizing CPU—You can disable Intel Hyper-Threading Technology for workloads that perform well with single-threaded CPUs, like some HPC applications.

NUMA—You can make use of non-uniform memory access (NUMA) on x2iezn.12xlarge instances. This advanced feature is worth exploring if you have a deep understanding of your application’s memory access patterns.

Available Now
Amazon EC2 X2iezn instances are now available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Tokyo), and Europe (Ireland) Regions. You can use On-Demand Instances, Reserved Instances, Savings Plan, and Spot Instances. Dedicated Instances and Dedicated Hosts are also available.

To learn more, visit our EC2 X2i Instances page, and please send feedback to the AWS forum for EC2 or through your usual AWS Support contacts.

– Channy

New – Replication for Amazon Elastic File System (EFS)

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-replication-for-amazon-elastic-file-system-efs/

Amazon Elastic File System (Amazon EFS) allows EC2 instances, AWS Lambda functions, and containers to share access to a fully-managed file system. First announced in 2015 and generally available in 2016, Amazon EFS delivers low-latency performance for a wide variety of workloads and can scale to thousands of concurrent clients or connections. Since the 2016 launch we have continued to listen and to innovate, and have added many new features and capabilities in response to your feedback. These include on-premises access via Direct Connect (2016), encryption of data at rest (2017), provisioned throughput and encryption of data in transit (2018), an infrequent access storage class (2019), IAM authorization & access points (2020), lower-cost one zone storage classes (2021), and more.

Introducing Replication
Today I am happy to announce that you can now use replication to automatically maintain copies of your EFS file systems for business continuity or to help you to meet compliance requirements as part of your disaster recovery strategy. You can set this up in minutes for new or existing EFS file systems, with replication either within a single AWS region or between two AWS regions in the same AWS partition.

Once configured, replication begins immediately. All replication traffic stays on the AWS global backbone, and most changes are replicated within a minute, with an overall Recovery Point Objective (RPO) of 15 minutes for most file systems. Replication does not consume any burst credits and it does not count against the provisioned throughput of the file system.

Configuring Replication
To configure replication, I open the Amazon EFS Console , view the file system that I want to replicate, and select the Replication tab:

I click Create replication, choose the desired destination region, and select the desired storage (Regional or One Zone). I can use the default KMS key for encryption or I can choose another one. I review my settings and click Create replication to proceed:

Replication begins right away and I can see the new, read-only file system immediately:

A new CloudWatch metric, TimeSinceLastSync, is published when the initial replication is complete, and periodically after that:

The replica is created in the selected region. I create any necessary mount targets and mount the replica on an EC2 instance:

EFS tracks modifications to the blocks (currently 4 MB) that are used to store files and metadata, and replicates the changes at a rate of up to 300 MB per second. Because replication is block-based, it is not crash-consistent; if you need crash-consistency you may want to take a look at AWS Backup.

After I have set up replication, I can change the lifecycle management, intelligent tiering, throughput mode, and automatic backup setting for the destination file system. The performance mode is chosen when the file system is created, and cannot be changed.

Initiating a Fail-Over
If I need to fail over to the replica, I simply delete the replication. I can do this from either side (source or destination), by clicking Delete and confirming my intent:

I enter delete, and click Delete replication to proceed:

The former read-only replica is now a writable file system that I can use as part of my recovery process. To fail-back, I create a replica in the original location, wait for replication to finish, and delete the replication.

I can also use the command line and the EFS APIs to manage replication. For example:

createreplication-configuration / CreateReplicationConfiguration – Establish replication for an existing file system.

describe-replication-configurations / DescribeReplicationConfigurations – See the replication configuration for a source or destination file system, or for all replication configurations in an AWS account. The data returned for a destination file system also includes LastReplicatedTimestamp, the time of the last successful sync.

delete-replication-configuration / DeleteReplicationConfiguration – End replication for a file system.

Available Now
This new feature is available now and you can start using it today in the AWS US East (N. Virginia), US East (Ohio), US West (N. California), US West (Oregon), Asia Pacific (Mumbai), Asia Pacific (Osaka), Asia Pacific (Seoul), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Canada (Central), Europe (Frankfurt), Europe (Ireland), Europe (London), Europe (Paris), Europe (Stockholm), South America (São Paulo), and GovCloud Regions.

You pay the usual storage fees for the original and replica file systems and any applicable cross-region or intra-region data transfer charges.

— Jeff;

Amazon GuardDuty Enhances Detection of EC2 Instance Credential Exfiltration

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-guardduty-enhances-detection-of-ec2-instance-credential-exfiltration/

Amazon GuardDuty is a threat detection service that continuously monitors for malicious activity and unauthorized behavior to protect your AWS accounts, workloads, and data stored in Amazon Simple Storage Service (Amazon S3). Informed by a multitude of public and AWS-generated data feeds and powered by machine learning, GuardDuty analyzes billions of events in pursuit of trends, patterns, and anomalies that are recognizable signs that something is amiss. You can enable it with a click and see the first findings within minutes.

Today, we are adding to GuardDuty the ability to detect when your Amazon Elastic Compute Cloud (Amazon EC2) instance credentials are being used from another AWS Account. EC2 instance credentials are the temporary credentials made available through the EC2 metadata service to any applications running on an instance, when an AWS Identity and Access Management (IAM) role is attached to it.

What Are the Risks?
When your workloads deployed on EC2 instances access AWS services, they use an access key, a secret access key, and a session token. The secure mechanism to pass access key credentials to your workloads is to define the permissions required by your workload, create one or several IAM policies with the permissions, attach the policies to an IAM role and, finally, attach the role to the instance.

Any process running on an EC2 instance with a role attached can retrieve the security credentials by calling the EC2 metadata service:

curl 169.254.169.254/latest/meta-data/iam/security-credentials/role_name
{
  "Code" : "Success",
  "LastUpdated" : "2021-09-05T18:24:45Z",
  "Type" : "AWS-HMAC",
  "AccessKeyId" : "AS...J5",
  "SecretAccessKey" : "r1...9m",
  "Token" : "IQ...z5Q==",
  "Expiration" : "2021-09-06T00:44:06Z"
}

These credentials are limited in time and in scope. They are valid for a maximum of six hours. They are limited to the scope of the permissions attached to the IAM role associated with the EC2 instance.

All AWS SDK are able to retrieve and renew such credentials automatically. No additional code is necessary in your application.

Now imagine that your application running on the EC2 instance is compromised and a malicious actor managed to access the instance’s meta data service. The malicious actor would extract the credentials. These credentials have the permissions you defined in the IAM role attached to the instance. Depending on your application, attackers might have the possibility to exfiltrate data from S3 or DynamoDB, to start or terminate EC2 instances, or even to create new IAM users or roles.

Since the launch of GuardDuty, it has detected when such credentials are used from IP addresses outside of AWS. Smart attackers therefore might hide their activity from another AWS account to operate outside of the sight of GuardDuty. Starting today, GuardDuty also detects when the credentials are used from other AWS accounts, inside the AWS network.

What Alerts Are Generated?
There are legitimate reasons why the source IP address communicating with AWS Services APIs might be different than the EC2 instance IP address. Think about complex network topologies that route traffic to one or multiple VPCs; AWS Transit Gateway, or AWS Direct Connect for example. In addition, multi-Region configurations, or not using AWS Organizations, makes it non trivial to detect if the AWS account using the credentials belongs to you or not. Large companies have implemented their own solution to detect such security compromises, but these type of solutions are not easy to build and to maintain. Only a handful of organizations have the resources required to tackle this challenge. When they do so, they distract their engineering efforts from their core business. This is why we decided to address this.

Starting today, GuardDuty generates alerts when it detects a misuse of EC2 instance credentials. When the credentials are used from an affiliated account, the alert is labeled as medium-severity. Otherwise, a high-severity alert is generated. Affiliated accounts are accounts monitored by the same GuardDuty administrator account, also known as GuardDuty member accounts. They might be part of your organization or not.

In Practice
To learn how it’s working, let’s capture and exfiltrate a set of EC2 credentials from one of my EC2 instances. I use SSH to connect to one of my instances, and I use curl to retrieve the credentials, as shown earlier:

curl 169.254.169.254/latest/meta-data/iam/security-credentials/role_name
{
  "Code" : "Success",
  "LastUpdated" : "2021-09-05T18:24:45Z",
  "Type" : "AWS-HMAC",
  "AccessKeyId" : "AS...J5",
  "SecretAccessKey" : "r1...9m",
  "Token" : "IQ...z5Q==",
  "Expiration" : "2021-09-06T00:44:06Z"
}

The instance has an IAM role with permissions allowing to read S3 buckets in this AWS account. I copy and paste the credentials. Then I connect to another EC2 instance running in a different AWS account, not affiliated with the same GuardDuty administrator account. I use SSH to connect to that other instance, and then I configure the AWS CLI with the compromised credentials. I attempt to access a private S3 bucket.


# first verify I do not have access 
[ec2-user@ip-1-1-0-79 ~]$ aws s3 ls s3://my-private-bucket

An error occurred (AccessDenied) when calling the ListObjectsV2 operation: Access Denied

# then I configure the CLI using the compromised credentials
[ec2-user@ip-1-1-0-79 ~]$ aws configure
AWS Access Key ID [None]: AS...J5
AWS Secret Access Key [None]: r1...9m
Default region name [None]: us-east-1
Default output format [None]:

[ec2-user@ip-1-1-0-79 ~]$ aws configure set aws_session_token IQ...z5Q==

# Finally, I attempt to access S3 again
[ec2-user@ip-1-1-0-79 ~]$ aws s3 ls s3://my-private-bucket
                     PRE folder1/
                     PRE folder2/
                     PRE folder3/
2021-01-22 16:37:48 6148 .DS_Store

Shortly after, I use the AWS Management Console to access GuardDuty in the AWS account where I stole the credentials. I can verify a high-severity alert was generated.

GuardDuty EC2 credentials exfiltration alarm

And So What?
Attackers may extract credentials when they have remote code execution (RCE), local presence on the instance, or by exploiting application-level vulnerabilities like Server Side Request Forgery (SSRF) and XML External Entity (XXE) injection. There are multiple methods to mitigate RCE or local access, including rebuilding the instances from a secured and patched AMI to eliminate remote access, rotate access credentials, and so on. When the vulnerability is at the application level, you or the application vendor are required to patch the application code to eliminate the vulnerability.

When you receive an alert indicating a risk of compromised credentials, the first thing to do is to verify the account ID. Is it one of your company accounts or not? During the analysis, when the business case allows, you may terminate the compromised instances or shut down the application. This prevents the attacker from extracting renewed instance credentials upon expiration. When in doubt, contact the AWS Trust & Safety team using the Report Amazon AWS abuse form or by contacting [email protected]. Provide all the necessary information, including the suspicious AWS account ID, logs in plaintext, and so on, when you submit your request.

Availability
This new ability is available in all AWS Regions at no additional cost. It is enabled by default when GuardDuty is already enabled on your AWS account.

Otherwise, enable GuardDuty now, and start the 30-day trial period.

— seb

A New AWS Console Home Experience

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/a-new-aws-console-home-experience/

If you are reading this blog, there is a high chance you frequently use the AWS Management Console. I taught AWS classes for years. During classes, students’ first hands-on experience with the AWS Cloud happened on the console, and I bet yours did too.

Until today, the home page of the console showed your most recently used services and a set of static links organized in sections, such as Getting Started with AWS, Build a Solution, or Explore AWS with links to training courses. However, we learned from our data that their usage is very different depending on your profile. You also told us it is cumbersome and time-consuming to navigate to different parts of the console to get an overview of important information for you.

We listened to your feedback, and I’m happy to announce a redesigned home page for the AWS Management Console. This new home page experience includes dynamic content, can be customized, and includes data from multiple AWS Regions.

The screenshot below shows the default view of this new console home page:

New console default layout

New console homepage action

The new Console Home is made of widgets. I may choose which widget to display on the page and where to include it. I may use the actions in the Actions drop down to customize my home page.

I may move and arrange widgets on the home page to organize the content as I want. When I click on the three little dots on the widget title bar, I may choose to remove the widget or resize it. I have the choice between Regular view and Extended view.

New console resize widget

At launch, the console provides eight widgets, and we will add more over time. Three widgets provide me with static links to learn how to build a solution or to explore AWS (Welcome to AWS, Build a Solution and Explore AWS). The other five are dynamic; their content depends on the usage of AWS by my applications and infrastructure:

  • AWS Health: this widget provides information on important events and changes
  • Cost and usage: this widget provides an overview of service costs, with a break down per AWS service.
  • Favorites: this widget shows a list of services that I have bookmarked
  • Recently visited: this widget provides the list of top recently visited services
  • Trusted Advisor: this widget provides recommendations to follow AWS best practices

AWS News Console List of widgets

As usual, we pay attention to the importance of not disturbing existing workflows and habits. You can use the new Console Home after opt-in. You can revert back to the old console home with a simple click.

This new Console Home is the first step to bring you more relevant content on this very first page you see every day. Stay tuned for more.

The new Console Home is available today in all AWS Regions at no additional cost. Go and customize your console homepage today.

— seb

New – Amazon EC2 Hpc6a Instance Optimized for High Performance Computing

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-hpc6a-instance-optimized-for-high-performance-computing/

High Performance Computing (HPC) allows scientists and engineers to solve complex, compute-intensive problems such as computational fluid dynamics (CFD), weather forecasting, and genomics. HPC applications typically require instances with high memory bandwidth, a low latency, high bandwidth network interconnect and access to a fast parallel file system.

Many customers have turned to AWS to run their HPC workloads. For example, Descartes Labs used AWS to power a TOP500 LINPACK benchmarking (the most powerful commercially available computer systems) run that delivered 1.93 PFLOPS, landing at position 136 on the TOP500 list in June 2019. That run made use of 41,472 cores on a cluster of Amazon EC2 C5 instances. Last year Descartes Labs ran the LINPACK benchmark again and placed within the top 40 on the June 2021 TOP500 list with 172,692 cores on a cluster of EC2 instances, which represents a 417 percent performance increase in just two years.

AWS enables you to increase the speed of research and reduce time-to-results by running HPC in the cloud and scaling to tens of thousands of parallel tasks that wouldn’t be practical in most on-premises environments. AWS helps you reduce costs by providing CPU, GPU, and FPGA instances on-demand, Elastic Fabric Adapter (EFA), an EC2 network device that improves throughput and scaling tightly coupled workloads, and AWS ParallelCluster, an open-source cluster management tool that makes it easy for you to deploy and manage HPC clusters on AWS.

Announcing EC2 Hpc6a Instances for HPC Workloads
Customers today across various industries use compute-optimized EFA-enabled Amazon EC2 instances (for example, C5n, R5n, M5n, and M5zn) to maximize the performance of a variety of HPC workloads, but as these workloads scale to tens of thousands of cores, cost-efficiency becomes increasingly important. We have found that customers are not only looking to optimize performance for their HPC workloads but want to optimize costs as well.

As we pre-announced in November 2021, Hpc6a, a new HPC-optimized EC2 instance, is generally available beginning today. This instance delivers 100 Gbps networking through EFA with 96 third-generation AMD EPYC™ processor (Milan) cores with 384 GB RAM, and offers up to 65 percent better price-performance over comparable x86-based compute-optimized instances.
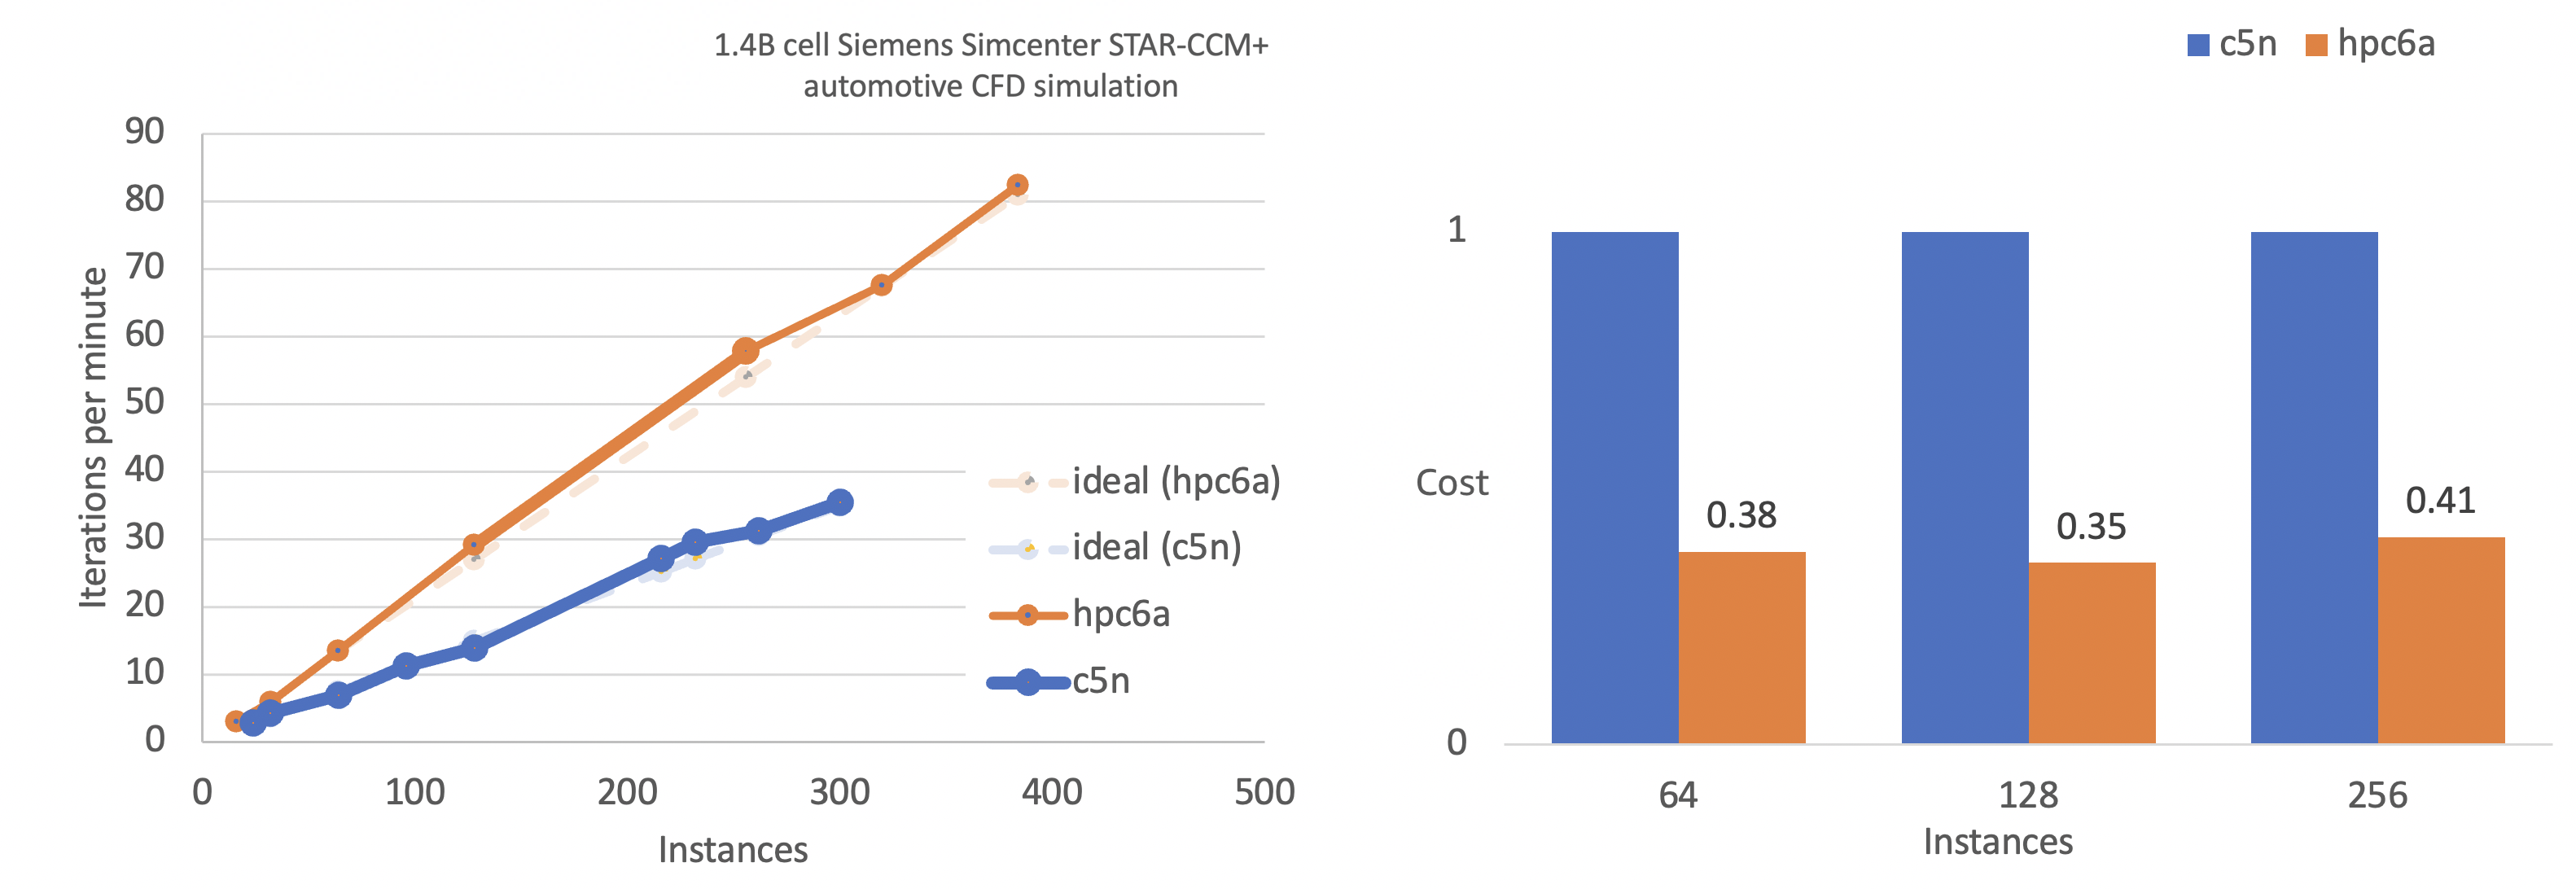
You can launch Hpc6a instances today in the US East (Ohio) and GovCloud (US-West) Regions in On-Demand and Dedicated Hosting or as part of a Savings Plan. Here are the detailed specs:

Instance Name CPUs* RAM EFA Network Bandwidth Attached Storage
hpc6a.48xlarge 96 384 GiB Up to 100 Gbps EBS Only

*Hpc6a instances have simultaneous multi-threading disabled to optimize for HPC codes. This means that unlike other EC2 instances, Hpc6a vCPUs are physical cores, not threads.

To enable predictable thread performance and efficient scheduling for HPC workloads, simultaneous multi-threading is disabled. Thanks to AWS Nitro System, no cores are held back for the hypervisor, making all cores available to your code.

Hpc6a instances introduce a number of targeted features to deliver cost and performance optimizations for customers running tightly coupled HPC workloads that rely on high levels of inter-instance communications. These instances enable EFA networking bandwidth of 100 Gbps and are designed to efficiently scale large tightly coupled clusters within a single Availability Zone.

We hear from many of our engineering customers, such as those in the automotive sector, that they want to reduce the need for physical testing and move towards an increasingly virtual simulation-based product design process faster at a lower cost.

According to our benchmarking results for Siemens Simcenter STAR-CCM+ automotive CFD simulation, when the Hpc6a scales up to 400 nodes (approximately 40,000 cores), with the help of EFA networking, it is able to maintain approximately 100 percent scaling efficiency. Hpc6a instance shows 70 percent lower cost compared to c5n, meaning companies can deliver new designs faster and at a lower cost when using Hpc6a instances. This means companies can deliver new designs faster and at a lower cost when using Hpc6a instances.

You can use the Hpc6a instance with AMD EPYC third-generation (Milan) processors to run your largest and most complex HPC simulations on EC2 and optimize for cost and performance. Customers can also use the new Hpc6a instances with AWS Batch and AWS ParallelCluster to simplify workload submission and cluster creation.

To learn more, visit our Hpc6a instance page and get in touch with our HPC team, AWS re:Post for EC2, or through your usual AWS Support contacts.

— Channy

Amazon Elastic Kubernetes Service Adds IPv6 Networking

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-elastic-kubernetes-service-adds-ipv6-networking/

Starting today, you can deploy applications that use IPv6 address space on Amazon Elastic Kubernetes Service (EKS).

Many of our customers are standardizing Kubernetes as their compute infrastructure platform for cloud and on-premises applications. Amazon EKS makes it easy to deploy containerized workloads. It provides highly available clusters and automates tasks such as patching, node provisioning, and updates.

Kubernetes uses a flat networking model that requires each pod to receive an IP address. This simplified approach enables low-friction porting of applications from virtual machines to containers but requires a significant number of IP addresses that many private VPC IPv4 networks are not equipped to handle. Some cluster administrators work around this IPv4 space limitation by installing container network plugins (CNI) that virtualize IP addresses a layer above the VPC, but this architecture limits an administrator’s ability to effectively observe and troubleshoot applications and has a negative impact on network performance at scale. Further, to communicate with internet services outside the VPC, traffic from IPv4 pods is routed through multiple network hops before reaching its destination, which adds latency and puts a strain on network engineering teams who need to maintain complex routing setups.

To avoid IP address exhaustion, minimize latency at scale, and simplify routing configuration, the solution is to use IPv6 address space.

IPv6 is not new. In 1996, I bought my first book on “IPng, Internet Protocol Next Generation”, as it was called 25 years ago. It provides a 64-bit address space, allowing 3.4 x 10^38 possible IP addresses for our devices, servers, or containers. We could assign an IPv6 address to every atom on the surface of the planet and still have enough addresses left to do another 100-plus Earths.

IPng Internet protocol Next Generation bookThere are a few advantages to using Amazon EKS clusters with an IPv6 network. First, you can run more pods on one single host or subnet without the risk of exhausting all available IPv4 addresses available in your VPC. Second, it allows for lower-latency communications with other IPv6 services, running on-premises, on AWS, or on the internet, by avoiding an extra NAT hop. Third, it relieves network engineers of the burden of maintaining complex routing configurations.

Kubernetes cluster administrators can focus on migrating and scaling applications without spending efforts working around IPv4 limits. Finally, pod networking is configured so that the pods can communicate with IPv4-based applications outside the cluster, allowing you to adopt the benefits of IPv6 on Amazon EKS without requiring that all dependent services deployed across your organization are first migrated to IPv6.

As usual, I built a short demo to show you how it works.

How It Works
Before I get started, I create an IPv6 VPC. I use this CDK script to create an IPv6-enabled VPC in a few minutes (thank you Angus Lees for the code). Just install CDK v2 (npm install -g aws-cdk@next) and deploy the stack (cdk bootstrap && cdk deploy).

When the VPC with IPv6 is created, I use the console to configure auto-assignment of IPv6 addresses to resources deployed in the public subnets (I do this for each public subnet).

auto assign IPv6 addresses in subnet

I take note of the subnet IDs created by the CDK script above (they are listed in the output of the script) and define a couple of variables I’ll use throughout the demo. I also create a cluster IAM role and a node IAM role, as described in the Amazon EKS documentation. When you already have clusters deployed, these two roles exist already.

I open a Terminal and type:


CLUSTER_ROLE_ARN="arn:aws:iam::0123456789:role/EKSClusterRole"
NODE_ROLE_ARN="arn:aws:iam::0123456789:role/EKSNodeRole"
SUBNET1="subnet-06000a8"
SUBNET2="subnet-03000cc"
CLUSTER_NAME="AWSNewsBlog"
KEYPAIR_NAME="my-key-pair-name"

Next, I create an Amazon EKS IPv6 cluster. In a terminal, I type:


aws eks create-cluster --cli-input-json "{
\"name\": \"${CLUSTER_NAME}\",
\"version\": \"1.21\",
\"roleArn\": \"${CLUSTER_ROLE_ARN}\",
\"resourcesVpcConfig\": {
\"subnetIds\": [
    \"${SUBNET1}\", \"${SUBNET2}\"
],
\"endpointPublicAccess\": true,
\"endpointPrivateAccess\": true
},
\"kubernetesNetworkConfig\": {
    \"ipFamily\": \"ipv6\"
}
}"

{
    "cluster": {
        "name": "AWSNewsBlog",
        "arn": "arn:aws:eks:us-west-2:486652066693:cluster/AWSNewsBlog",
        "createdAt": "2021-11-02T17:29:32.989000+01:00",
        "version": "1.21",

...redacted for brevity...

        "status": "CREATING",
        "certificateAuthority": {},
        "platformVersion": "eks.4",
        "tags": {}
    }
}

I use the describe-cluster while waiting for the cluster to be created. When the cluster is ready, it has "status" : "ACTIVE"

aws eks describe-cluster --name "${CLUSTER_NAME}"

Then I create a node group:

aws eks create-nodegroup                       \
        --cluster-name ${CLUSTER_NAME}         \
        --nodegroup-name AWSNewsBlog-nodegroup \
        --node-role ${NODE_ROLE_ARN}           \
        --subnets "${SUBNET1}" "${SUBNET2}"    \
        --remote-access ec2SshKey=${KEYPAIR_NAME}
		
{
    "nodegroup": {
        "nodegroupName": "AWSNewsBlog-nodegroup",
        "nodegroupArn": "arn:aws:eks:us-west-2:0123456789:nodegroup/AWSNewsBlog/AWSNewsBlog-nodegroup/3ebe70c7-6c45-d498-6d42-4001f70e7833",
        "clusterName": "AWSNewsBlog",
        "version": "1.21",
        "releaseVersion": "1.21.4-20211101",

        "status": "CREATING",
        "capacityType": "ON_DEMAND",

... redacted for brevity ...

}		

Once the node group is created, I see two EC2 instances in the console. I use the AWS Command Line Interface (CLI) to verify that the instances received an IPv6 address:

aws ec2 describe-instances --query "Reservations[].Instances[? State.Name == 'running' ][].NetworkInterfaces[].Ipv6Addresses" --output text 

2600:1f13:812:0000:0000:0000:0000:71eb
2600:1f13:812:0000:0000:0000:0000:3c07

I use the kubectl command to verify the cluster from a Kubernetes point of view.

kubectl get nodes -o wide

NAME                                       STATUS   ROLES    AGE     VERSION               INTERNAL-IP                              EXTERNAL-IP    OS-IMAGE         KERNEL-VERSION                CONTAINER-RUNTIME
ip-10-0-0-108.us-west-2.compute.internal   Ready    <none>   2d13h   v1.21.4-eks-033ce7e   2600:1f13:812:0000:0000:0000:0000:2263   18.0.0.205   Amazon Linux 2   5.4.149-73.259.amzn2.x86_64   docker://20.10.7
ip-10-0-1-217.us-west-2.compute.internal   Ready    <none>   2d13h   v1.21.4-eks-033ce7e   2600:1f13:812:0000:0000:0000:0000:7f3e   52.0.0.122   Amazon Linux 2   5.4.149-73.259.amzn2.x86_64   docker://20.10.7

Then I deploy a Pod. I follow these steps in the EKS documentation. It deploys a sample nginx web server.

kubectl create namespace aws-news-blog
namespace/aws-news-blog created

# sample-service.yml is available at https://docs.aws.amazon.com/eks/latest/userguide/sample-deployment.html
kubectl apply -f  sample-service.yml 
service/my-service created
deployment.apps/my-deployment created

kubectl get pods -n aws-news-blog -o wide
NAME                             READY   STATUS    RESTARTS   AGE   IP                           NODE                                       NOMINATED NODE   READINESS GATES
my-deployment-5dd5dfd6b9-7rllg   1/1     Running   0          17m   2600:0000:0000:0000:405b::2   ip-10-0-1-217.us-west-2.compute.internal   <none>           <none>
my-deployment-5dd5dfd6b9-h6mrt   1/1     Running   0          17m   2600:0000:0000:0000:46f9::    ip-10-0-0-108.us-west-2.compute.internal   <none>           <none>
my-deployment-5dd5dfd6b9-mrkfv   1/1     Running   0          17m   2600:0000:0000:0000:46f9::1   ip-10-0-0-108.us-west-2.compute.internal   <none>           <none>

I take note of the IPv6 address of my pods, and try to connect it from my laptop. As my awesome service provider doesn’t provide me with an IPv6 at home yet, the connection fails. This is expected as the pods do not have an IPv4 address at all. Notice the -g option telling curl to not consider : in the IP address as the separator for the port number and -6 to tell curl to connect through IPv6 only (required when you provide curl with a DNS hostname).

curl -g -6 http://\[2600:0000:0000:35000000:46f9::1\]
curl: (7) Couldn't connect to server

To test IPv6 connectivity, I start a dual stack (IPv4 and IPv6) EC2 instance in the same VPC as the cluster. I SSH connect to the instance and try the curl command again. I see I receive the default HTML page served by nginx. IPv6 connectivity to the pod works!

curl -g -6 http://\[2600:0000:0000:35000000:46f9::1\]
<!DOCTYPE html>
<html>
<head>
<title>Welcome to nginx!</title>

... redacted for brevity ...

<p><em>Thank you for using nginx.</em></p>
</body>
</html>

If it does not work for you, verify the security group for the cluster EC2 nodes and be sure it has a rule allowing incoming connections on port TCP 80 from ::/0.

A Few Things to Remember
Before I wrap up, I’d like to answer some frequent questions received from customers who have already experimented with this new capability:

Pricing and Availability
IPv6 support for your Amazon Elastic Kubernetes Service (EKS) cluster is available today in all AWS Regions where Amazon EKS is available, at no additional cost.

Go try it out and build your first IPv6 cluster today.

— seb