Tag Archives: Uncategorized

What Anthropic’s Mythos Means for the Future of Cybersecurity

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/what-anthropics-mythos-means-for-the-future-of-cybersecurity.html

Two weeks ago, Anthropic announced that its new model, Claude Mythos Preview, can autonomously find and weaponize software vulnerabilities, turning them into working exploits without expert guidance. These were vulnerabilities in key software like operating systems and internet infrastructure that thousands of software developers working on those systems failed to find. This capability will have major security implications, compromising the devices and services we use every day. As a result, Anthropic is not releasing the model to the general public, but instead to a limited number of companies.

The news rocked the internet security community. There were few details in Anthropic’s announcement, angering many observers. Some speculate that Anthropic doesn’t have the GPUs to run the thing, and that cybersecurity was the excuse to limit its release. Others argue Anthropic is holding to its AI safety mission. There’s hype and counterhype, reality and marketing. It’s a lot to sort out, even if you’re an expert.

We see Mythos as a real but incremental step, one in a long line of incremental steps. But even incremental steps can be important when we look at the big picture.

How AI Is Changing Cybersecurity

We’ve written about shifting baseline syndrome, a phenomenon that leads people—the public and experts alike—to discount massive long-term changes that are hidden in incremental steps. It has happened with online privacy, and it’s happening with AI. Even if the vulnerabilities found by Mythos could have been found using AI models from last month or last year, they couldn’t have been found by AI models from five years ago.

The Mythos announcement reminds us that AI has come a long way in just a few years: The baseline really has shifted. Finding vulnerabilities in source code is the type of task that today’s large language models excel at. Regardless of whether it happened last year or will happen next year, it’s been clear for a while this kind of capability was coming soon. The question is how we adapt to it.

We don’t believe that an AI that can hack autonomously will create permanent asymmetry between offense and defense; it’s likely to be more nuanced than that. Some vulnerabilities can be found, verified, and patched automatically. Some vulnerabilities will be hard to find but easy to verify and patch—consider generic cloud-hosted web applications built on standard software stacks, where updates can be deployed quickly. Still others will be easy to find (even without powerful AI) and relatively easy to verify, but harder or impossible to patch, such as IoT appliances and industrial equipment that are rarely updated or can’t be easily modified.

Then there are systems whose vulnerabilities will be easy to find in code but difficult to verify in practice. For example, complex distributed systems and cloud platforms can be composed of thousands of interacting services running in parallel, making it difficult to distinguish real vulnerabilities from false positives and to reliably reproduce them.

So we must separate the patchable from the unpatchable, and the easy to verify from the hard to verify. This taxonomy also provides us guidance for how to protect such systems in an era of powerful AI vulnerability-finding tools.

Unpatchable or hard to verify systems should be protected by wrapping them in more restrictive, tightly controlled layers. You want your fridge or thermostat or industrial control system behind a restrictive and constantly updated firewall, not freely talking to the internet.

Distributed systems that are fundamentally interconnected should be traceable and should follow the principle of least privilege, where each component has only the access it needs. These are bog-standard security ideas that we might have been tempted to throw out in the era of AI, but they’re still as relevant as ever.

Rethinking Software Security Practices

This also raises the salience of best practices in software engineering. Automated, thorough, and continuous testing was always important. Now we can take this practice a step further and use defensive AI agents to test exploits against a real stack, over and over, until the false positives have been weeded out and the real vulnerabilities and fixes are confirmed. This kind of VulnOps is likely to become a standard part of the development process.

Documentation becomes more valuable, as it can guide an AI agent on a bug-finding mission just as it does developers. And following standard practices and using standard tools and libraries allows AI and engineers alike to recognize patterns more effectively, even in a world of individual and ephemeral instant software—code that can be generated and deployed on demand.

Will this favor offense or defense? The defense eventually, probably, especially in systems that are easy to patch and verify. Fortunately, that includes our phones, web browsers, and major internet services. But today’s cars, electrical transformers, fridges, and lampposts are connected to the internet. Legacy banking and airline systems are networked.

Not all of those are going to get patched as fast as needed, and we may see a few years of constant hacks until we arrive at a new normal: where verification is paramount and software is patched continuously.

This essay was written with Barath Raghavan, and originally appeared in IEEE Spectrum.

Friday Squid Blogging: How Squid Survived Extinction Events

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/friday-squid-blogging-how-squid-survived-extinction-events.html

Science news:

Scientists have finally cracked a long-standing mystery about squid and cuttlefish evolution by analyzing newly sequenced genomes alongside global datasets. The research reveals that these bizarre, intelligent creatures likely originated deep in the ocean over 100 million years ago, surviving mass extinction events by retreating into oxygen-rich deep-sea refuges. For millions of years, their evolution barely changed—until a dramatic post-extinction boom sparked rapid diversification as they moved into new shallow-water habitats.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Blog moderation policy.

Hiding Bluetooth Trackers in Mail

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/hiding-bluetooth-trackers-in-mail.html

It was used to track a Dutch naval ship:

Dutch journalist Just Vervaart, working for regional media network Omroep Gelderland, followed the directions posted on the Dutch government website and mailed a postcard with a hidden tracker inside. Because of this, they were able to track the ship for about a day, watching it sail from Heraklion, Crete, before it turned towards Cyprus. While it only showed the location of that one vessel, knowing that it was part of a carrier strike group sailing in the Mediterranean could potentially put the entire fleet at risk.

[…]

Navy officials reported that the tracker was discovered within 24 hours of the ship’s arrival, during mail sorting, and was eventually disabled. Because of this incident, the Dutch authorities now ban electronic greeting cards, which, unlike packages, weren’t x-rayed before being brought on the ship.

FBI Extracts Deleted Signal Messages from iPhone Notification Database

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/fbi-extracts-deleted-signal-messages-from-iphone-notification-database.html

404 Media reports (alternate site):

The FBI was able to forensically extract copies of incoming Signal messages from a defendant’s iPhone, even after the app was deleted, because copies of the content were saved in the device’s push notification database….

The news shows how forensic extraction—­when someone has physical access to a device and is able to run specialized software on it—­can yield sensitive data derived from secure messaging apps in unexpected places. Signal already has a setting that blocks message content from displaying in push notifications; the case highlights why such a feature might be important for some users to turn on.

“We learned that specifically on iPhones, if one’s settings in the Signal app allow for message notifications and previews to show up on the lock screen, [then] the iPhone will internally store those notifications/message previews in the internal memory of the device,” a supporter of the defendants who was taking notes during the trial told 404 Media.

A low-tech trick with sshfs

Post Syndicated from Григор original http://www.gatchev.info/blog/?p=2690

Sometimes old, low-tech sysadmin tricks do excellent job. 🙂

A friend of mine asked for help. Time had came for his company to grow up, and it had opened several offices across Europe. However, their IT system wasn’t up to that.

Their specialized software currently ran on a local server in their office. Now, every office had a server – but they had to use together a central database. The software could share a database between several instances, but access to it was built directly in the executable and required a local path. The company behind it had offered to add a client-server database model, but the cost was prohibitive.

Luckily, all of it ran over Linux, which has a huge set of tools for everything. I decided on a very simple and dumb solution. Mounted the directory with the database as local on the office servers through sshfs. It uses ssh as a transport agent, so the protection of data through Internet is very good.

sshfs [email protected]:/some/path/to/database /local/mount/path

To avoid the need for ssh login, I generated (as the user that mounts the directory) a key for every remote server:

su db_dir_mount_user
ssh-keygen -t rsa -b 4096

(It asks for some action from you, and finally generates the key in the .ssh subdirectory in the home directory of the user, as two files: id_rsa and id_rsa.pub.)

Then, I authorized these keys at the server with the database. I went to it, and there (as database_user) copied the id_rsa.pub file from the remote server to the server with the database, and added it to the file .ssh/authorized_keys:

su database_user
rsync -avz [email protected]:/home/db_dir_mount_user/.ssh/id_rsa.pub .ssh/local-server-1.id_rsa.pub
cat local-server-1.id_rsa.pub >> authorized_keys

So far, so well. However, when I started sshfs, it refused to work with a message:

fuse: device not found, try 'modprobe fuse' first

Turned out, the local office servers with the software were actually LXC containers. The company had one physical (well, and one backup 🙂 ) server per office, with several LXC containers running different things on it. Both the software container and the mother OS had fuse (which is required by sshfs) installed, but that was not enough.

The problem turned out to be a fuse device missing from the /dev directory. Which was easy to solve:

mknod /dev/fuse c 10 229

After that, everything went without a glitch. The experiments showed that the query times are low enough for production usage.

Yes, if this company continues to grow, rewriting the database communication as a client-server model will be unavoidable. However, this trick gave them some time to grow up more and find the money needed. 🙂

How to clone an AWS CloudHSM cluster across Regions

Post Syndicated from Desiree Brunner original https://aws.amazon.com/blogs/security/how-to-clone-an-aws-cloudhsm-cluster-across-regions-2/

Important: As of January 1, 2025, Client SDK 3 tools (CMU and KMU) are no longer supported. This guide has been updated to use Client SDK 5 commands exclusively. Ensure you’re using the latest Client SDK 5 version (5.17 or later) for the most recent features and security improvements.

You can use AWS CloudHSM to generate, store, import, export, and manage your cryptographic keys. It also permits hash functions to compute message digests and hash-based message authentication codes (HMACs) and supports cryptographically signing data and verifying signatures. To help ensure redundancy of data and simplification of the disaster recovery process, AWS recommends you to clone your CloudHSM cluster into a different AWS Region. By doing this, you can synchronize keys, including non-exportable keys, across Regions. Non-exportable keys can only be synchronized to cloned clusters. Non-exportable keys are keys that can never leave the CloudHSM device in plaintext. They reside on the CloudHSM device and are encrypted for security purposes.

In this post, I show you how to set up one cluster in Region 1 and how to use the CopyBackupToRegion feature to clone the cluster and hardware security modules (HSMs) to a virtual private cloud (VPC) in Region 2.

Note: This post doesn’t include instructions on how to set up a cross-Region VPC to synchronize HSMs across the two cloned clusters. If you need to set up a cross-Region VPC, see Building a Scalable and Secure Multi-VPC AWS Network Infrastructure.

Solution overview

You clone a cluster to another Region in a two-step process:

  1. Copy a backup to the destination Region
  2. Create a new cluster from this backup

To complete this solution, you can use either the AWS Command Line Interface (AWS CLI) or the CloudHSM API. For this post, I show you how to use the AWS CLI to copy the cluster backup from Region 1 to Region 2 and then launch a new cluster from that copied backup.
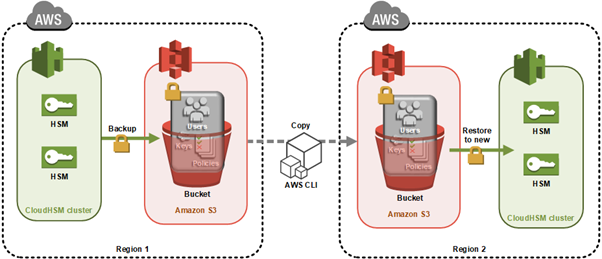
Figure 1 illustrates the process described in this post.

Figure 1: Architecture diagram

Figure 1: Architecture diagram

Here’s how the process works:

  1. CloudHSM creates a backup of the cluster and stores it in an Amazon Simple Storage Service (Amazon S3) bucket owned by the CloudHSM service.
  2. You use the AWS CLI API command to copy the backup to another Region.
  3. When the backup is completed, you use that backup to then create a new cluster and HSMs.
Note: Backups can’t be copied across partitions like the AWS GovCloud Regions, China Region and AWS European Sovereign Cloud.

As with all cluster backups, when you copy the backup to a new Region, it’s stored in an S3 bucket owned by a CloudHSM account. CloudHSM manages the security and storage of cluster backups for you. This means the backup in both Regions will also have the durability of Amazon S3, which has 99.999999999% durability. The backup in Region 2 will be encrypted and secured in the same way as your backup in Region 1. You can read more about the encryption process of your CloudHSM backups in AWS CloudHSM cluster backups.
Any HSMs created in this cloned cluster will have the same users and keys as the original cluster at the time the backup was taken. From this point on, you must manually keep the cloned clusters in sync. Specifically:

  • If you create users after creating your new cluster from the backup, you must create them on both clusters manually.
  • If you change the password for a user in one cluster, you must change the password on the cloned clusters to match.
  • If you create more keys in one cluster, you must sync them to at least one HSM in the cloned cluster. After you sync the key from cluster 1 to cluster 2, the CloudHSM automated cluster synchronization will take care of syncing the keys in the second cluster.

Prerequisites

Before starting, ensure you have the following in place:

Note: Syncing keys across clusters in more than one Region will only work if all clusters are created from the same backup. This is because synchronization requires the same secret key—called a masking key—to be present on the source and destination HSM. The masking key is specific to each cluster. It can’t be exported, and can’t be used for any purpose other than synchronizing keys across HSMs in a cluster.

Step 1: Create your first cluster in Region 1

The first step in cloning your CloudHSM cluster is to create the initial cluster—which will serve as the foundation for your cross-Region deployment—in your source Region.

Create the cluster

Replace <SUBNET_ID_1> with one of your private subnets. Make a note of the cluster ID to use later:
aws cloudhsmv2 create-cluster --hsm-type hsm2m.medium --subnet-ids <SUBNET_ID_1>

Launch the EC2 client

Launch an Amazon Elastic Compute Cloud (Amazon EC2) instance in your public subnet. See Step 1 of Get started with Amazon EC2 for detailed steps.

Create the first HSM

Replace <CLUSTER_ID> with the ID you recorded earlier and <AVAILABILITY_ZONE> with the Availability Zone matching your private subnet (for example, us-east-1a):
aws cloudhsmv2 create-hsm --cluster-id <CLUSTER_ID> --availability-zone <AVAILABILITY_ZONE>

Initialize the cluster

Before you initialize the cluster, create a self-signed certificate and use it to sign the cluster’s certificate signing request (CSR). Once you have the signed certificate, initialize the cluster:

aws cloudhsmv2 initialize-cluster \
    --cluster-id <CLUSTER_ID> \
    --signed-cert file://<CLUSTER_ID>_CustomerHsmCertificate.crt \
    --trust-anchor file://customerCA.crt

Important: Copy the certificate used to sign your cluster’s CSR to to maintain a secure connection.

After the command completes, the cluster transitions to the Initialized state. Copy the certificate used to sign your cluster’s CSR to /opt/cloudhsm/etc so that the CloudHSM client can verify the cluster’s identity when you configure it in the next step:

sudo cp _CustomerHsmCertificate.crt /opt/cloudhsm/etc/
sudo cp customerCA.crt /opt/cloudhsm/etc/

Install the CloudHSM Client SDK 5

Download and install the latest CloudHSM Client SDK 5 (version 5.17 or later):
For example, for Amazon Linux 2023:

wget https://s3.amazonaws.com/cloudhsmv2-software/CloudHsmClient/Amzn2023/cloudhsm-cli-latest.amzn2023.x86_64.rpm
sudo yum install -y ./cloudhsm-cli-latest.amzn2023.x86_64.rpm

Configure the client

Configure the CloudHSM client with your HSM’s elastic network interface (ENI IP) address:
configure-cli -a <HSM_IP>

Activate the cluster

To activate the cluster, run the CloudHSM CLI in interactive mode.

cloudhsm-cli interactive

You can run user list to see the admin user, which is not yet activated.

aws-cloudhsm > user list
{
  "error_code": 0,
  "data": {
    "users": [
      {
        "username": "admin",
        "role": "unactivated-admin",
        "locked": "false",
        "mfa": [],
        "cluster-coverage": "full"
      },
      {
        "username": "app_user",
        "role": "internal(APPLIANCE_USER)",
        "locked": "false",
        "mfa": [],
        "cluster-coverage": "full"
      }
    ]
  }
}

Use the cluster activate command to set the initial admin password.

aws-cloudhsm > cluster activate
Enter password:<NewPassword>
Confirm password:<NewPassword>
{
  "error_code": 0,
  "data": "Cluster activation successful"
}

When completed, sign out using the command quit, then sign back in with the new password, using the command login --username admin --role admin.

After doing this, you can create the first crypto user (CU). You create the user by running the command: user create --username <USERNAME> --role crypto-user. For more information, see HSM user types for CloudHSM CLI. Crypto users are permitted to create and share keys on the CloudHSM.

When completed, sign out using the command quit.

Step 2: Create keys in Region 1

Create a non-exportable AES-256 key:

aws-cloudhsm > key generate-symmetric aes \
    --label aes-example \
    --key-length-bytes 32 \
    --attributes extractable=false

Make note of the key reference returned in the output, because you’ll need it for synchronization later.

Step 3: Trigger a backup of your cluster

To trigger a backup for Region 2:

  1. Add another HSM to your cluster in Region 1 (can be done using the AWS Management Console or AWS CLI)
  2. The backup will contain:
    • All users (crypto officers (COs), crypto users (CUs), and appliance users)
    • All key material on the HSMs
    • All configurations and policies
Note: The user portion is critical because keys can only be synced across clusters to the same user.

Record the backup ID to use later. You can find this in the CloudHSM console under Backups, or using the following command:

aws cloudhsmv2 describe-backups --cluster-id

To avoid unnecessary charges, you can delete the additional HSM after the backup is created.

Step 4: Copy your backup Between Regions

Before you can transfer the backup to your destination Region, you need to configure the appropriate IAM permissions to allow the copy operation.

IAM permissions

Ensure proper permissions are configured for your IAM role or user. You need CloudHSM administrator privileges. Here’s an example permissions policy:

{
   "Version": "2012-10-17",
   "Statement": {
      "Effect": "Allow",
      "Action": [
         "cloudhsm:*",
         "ec2:CreateNetworkInterface",
         "ec2:DescribeNetworkInterfaces",
         "ec2:DescribeNetworkInterfaceAttribute",
         "ec2:DetachNetworkInterface",
         "ec2:DeleteNetworkInterface",
         "ec2:CreateSecurityGroup",
         "ec2:AuthorizeSecurityGroupIngress",
         "ec2:AuthorizeSecurityGroupEgress",
         "ec2:RevokeSecurityGroupEgress",
         "ec2:DescribeSecurityGroups",
         "ec2:DeleteSecurityGroup",
         "ec2:CreateTags",
         "ec2:DescribeVpcs",
         "ec2:DescribeSubnets",
         "iam:CreateServiceLinkedRole"
      ],
      "Resource": "*"
   }
}

Copy the backup

To copy your backup from Region 1 to Region 2, you need:

  • The destination Region
  • The source cluster ID and backup ID (you can use either or both) found in the CloudHSM console

If you specify only the cluster ID, the most recent backup will be chosen. For a specific backup, use the backup ID.

aws cloudhsmv2 copy-backup-to-region \
    --destination-region <DESTINATION_REGION> \
    --backup-id <BACKUP_ID>

Example response:

{
    "DestinationBackup": {
        "SourceBackup": "backup-4kuraxsqetz",
        "SourceCluster": "cluster-kzlczlspnho",
        "CreateTimestamp": 1531742400,
        "SourceRegion": "us-east-1"
    }
}

After copying, you will see a new backup ID in your console. Use this to create your new cluster in Region 2:

aws cloudhsmv2 create-cluster \
    --hsm-type hsm2m.medium \
    --subnet-ids <SUBNET_ID_REGION_2> \
    --source-backup-id <BACKUP_ID_REGION_2> \

Certificate transfer

Copy the cluster certificate from the original cluster to the new Region:

  1. Open two terminal sessions (one for each HSM)
  2. Copy the certificate content from cluster 1
  3. Create and paste into a new file in cluster 2

The certificate is required for encrypted connections between your client and HSM instances.

Security group configuration

Add the cloned cluster’s Security Group to your EC2 client instance:

  1. Select the Security Group for your EC2 client in the EC2 console
  2. Choose “Add rules”
  3. Add a rule allowing traffic from the cluster’s Security Group ID on port 2225

Then retrieve the ENI IP address of the HSM in Region 2 using the following command, and make a note of the output—you will use it in the next step to configure cross-Region connectivity:

aws cloudhsmv2 describe-clusters \
    --filters clusterIds=<cluster_ID_region_2> \
    --region <region_2> \
    --query 'Clusters.Hsms.EniIp' \
    --output text

Step 5: Configure cross-Region connectivity

To enable the CloudHSM CLI to communicate with both clusters simultaneously, add the Region 2 cluster to your existing client configuration using the ENI IP address you retrieved in the previous step:

Step 6: Synchronize keys between clusters

To synchronize keys between your source and destination clusters, you first need to verify which users and keys exist before replicating them.

configure-cli add-cluster \
    --cluster-id <cluster_ID_region_2> \
    --endpoint <hsm_eni_ip_region_2> \
    --region <region_2>

The CloudHSM CLI will now communicate with both clusters simultaneously using the certificates already configured during the initial setup, enabling key synchronization using the masking key shared between cloned clusters.

List users and keys

First, verify users and list available keys:
# List all users
cloudhsm-cli user list

# List keys for specific user
cloudhsm-cli key list --username

Replicate keys

To replicate a key from Region 1 to Region 2:

cloudhsm-cli key replicate \
    --filter key-reference=<key_ref> \
    --source-cluster-id <source_cluster_ID> \
    --destination-cluster-id <destination_cluster_ID>

Verify the key replication by listing keys again:

cloudhsm-cli key list --username <username>

The output should show identical key references on both clusters. Repeat this process for any additional keys that you want to synchronize.

Points to remember

After cloning a cluster to a backup cluster, remember these important points:

  • Always manually update users across clusters after the initial backup
  • Use key replication for any keys created after the initial backup
  • Keep your Client SDK 5 tools updated for the latest features and security improvements
  • The January 1, 2025, end-of-support date for Client SDK 3 tools (CMU and KMU) means you should migrate to Client SDK 5 as soon as possible

Client SDK 5 supports ARM64 architecture on the following Linux distributions:

  • Amazon Linux 2023
  • Amazon Linux 2
  • Red Hat Enterprise Linux (RHEL) 8 (8.3+)
  • Red Hat Enterprise Linux (RHEL) 9 (9.2+)
  • Red Hat Enterprise Linux (RHEL) 10 (10.0+)
  • Ubuntu 22.04 LTS
  • Ubuntu 24.04 LTS
  • Debian 12
  • USE Linux Enterprise Server 15

Conclusion

You now have a fault-tolerant AWS CloudHSM environment with synchronized keys across Regions using the latest tools and best practices. By implementing this cross-Region cluster configuration, you gain improved disaster recovery capabilities, reduced risk of data loss, and enhanced business continuity for your cryptographic operations. This approach helps ensure that your critical cryptographic keys remain available even in the event of a Regional outage, providing the resilience that enterprise workloads demand.

If you have feedback about this post, submit comments in the Comments section below. For questions about this post, start a new thread on the AWS re:Post.

Desiree Brunner

Desiree Brunner

Desiree is a Security Specialist Solutions Architect working with regulated customers as part of the AWS EMEA Security & Compliance team. She builds on her background in DevOps and platform engineering to support her customers in designing secure, compliant cloud environments. Passionate about mental health and knowledge sharing, she regularly speaks at AWS events and supports teams on their cloud security journey.

Rickard Löfström

Rickard Löfström

Rickard guides enterprises in building secure cloud environments as a Specialist Solutions Architect in the AWS EMEA Security & Compliance team. He advises customers on implementing AWS security services, focusing on identity management, data protection, and infrastructure security controls. He enjoys translating complex security requirements into technical solutions that enable organizations to meet their security objectives while maintaining operational efficiency.

Is “Satoshi Nakamoto” Really Adam Back?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/is-satoshi-nakamoto-really-adam-back.html

The New York Times has a long article where the author lays out an impressive array of circumstantial evidence that the inventor of Bitcoin is the cypherpunk Adam Back.

I don’t know. The article is convincing, but it’s written to be convincing.

I can’t remember if I ever met Adam. I was a member of the Cypherpunks mailing list for a while, but I was never really an active participant. I spent more time on the Usenet newsgroup sci.crypt. I knew a bunch of the Cypherpunks, though, from various conferences around the world at the time. I really have no opinion about who Satoshi Nakamoto really is.

Mythos and Cybersecurity

Post Syndicated from B. Schneier original https://www.schneier.com/blog/archives/2026/04/mythos-and-cybersecurity.html

Last week, Anthropic pulled back the curtain on Claude Mythos Preview, an AI model so capable at finding and exploiting software vulnerabilities that the company decided it was too dangerous to release to the public. Instead, access has been restricted to roughly 50 organizations—Microsoft, Apple, Amazon Web Services, CrowdStrike and other vendors of critical infrastructure—under an initiative called Project Glasswing.

The announcement was accompanied by a barrage of hair-raising anecdotes: thousands of vulnerabilities uncovered across every major operating system and browser, including a 27-year-old bug in OpenBSD, a 16-year-old flaw in FFmpeg. Mythos was able to weaponize a set of vulnerabilities it found in the Firefox browser into 181 usable attacks; Anthropic’s previous flagship model could only achieve two.

This is, in many respects, exactly the kind of responsible disclosure that security researchers have long urged. And yet the public has been given remarkably little with which to evaluate Anthropic’s decision. We have been shown a highlight reel of spectacular successes. However, we can’t tell if we have a blockbuster until they let us see the whole movie.

For example, we don’t know how many times Mythos mistakenly flagged code as vulnerable. Anthropic said security contractors agreed with the AI’s severity rating 198 times, with an 89 per cent severity agreement. That’s impressive, but incomplete. Independent researchers examining similar models have found that AI that detects nearly every real bug also hallucinates plausible-sounding vulnerabilities in patched, correct code.

This matters. A model that autonomously finds and exploits hundreds of vulnerabilities with inhuman precision is a game changer, but a model that generates thousands of false alarms and non-working attacks still needs skilled and knowledgeable humans. Without knowing the rate of false alarms in Mythos’s unfiltered output, we cannot tell whether the examples showcased are representative.

There is a second, subtler problem. Large language models, including Mythos, perform best on inputs that resemble what they were trained on: widely used open-source projects, major browsers, the Linux kernel and popular web frameworks. Concentrating early access among the largest vendors of precisely this software is sensible; it lets them patch first, before adversaries catch up.

But the inverse is also true. Software outside the training distribution—industrial control systems, medical device firmware, bespoke financial infrastructure, regional banking software, older embedded systems—is exactly where out-of-the-box Mythos is likely least able to find or exploit bugs.

However, a sufficiently motivated attacker with domain expertise in one of these fields could nevertheless wield Mythos’s advanced reasoning capabilities as a force multiplier, probing systems that Anthropic’s own engineers lack the specialized knowledge to audit. The danger is not that Mythos fails in those domains; it is that Mythos may succeed for whoever brings the expertise.

Broader, structured access for academic researchers and domain specialists—cardiologists’ partners in medical device security, control-systems engineers, researchers in less prominent languages and ecosystems—would meaningfully reduce this asymmetry. Fifty companies, however well chosen, cannot substitute for the distributed expertise of the entire research community.

None of this is an indictment of Anthropic. By all appearances the company is trying to act responsibly, and its decision to hold the model back is evidence of seriousness.

But Anthropic is a private company and, in some ways, still a start-up. Yet it is making unilateral decisions about which pieces of our critical global infrastructure get defended first, and which must wait their turn.

It has finite staff, finite budget and finite expertise. It will miss things, and when the thing missed is in the software running a hospital or a power grid, the cost will be borne by people who never had a say.

The security problem is far greater than one company and one model. There’s no reason to believe that Mythos Preview is unique. (Not to be outdone, OpenAI announced that its new GPT-5.3-Codex is so dangerous that the model also will not be released to the general public.) And it’s unclear how much of an advance these new models represent. The security company Aisle was able to replicate many of Anthropic’s published anecdotes using smaller, cheaper, public AI models.

Any decisions we make about whether and how to release these powerful models are more than one company’s responsibility. Ultimately, this will probably lead to regulation. That will be hard to get right and requires a long process of consultation and feedback.

In the short term, we need something simpler: greater transparency and information sharing with the broader community. This doesn’t necessarily mean making powerful models like Claude Mythos widely available. Rather, it means sharing as much data and information as possible, so that we can collectively make informed decisions.

We need globally co-ordinated frameworks for independent auditing, mandatory disclosure of aggregate performance metrics and funded access for academic and civil-society researchers.

This has implications for national security, personal safety and corporate competitiveness. Any technology that can find thousands of exploitable flaws in the systems we all depend on should not be governed solely by the internal judgment of its creators, however well intentioned.

Until that changes, each Mythos-class release will put the world at the edge of another precipice, without any visibility into whether there is a landing out of view just below, or whether this time the drop will be fatal. That is not a choice a for-profit corporation should be allowed to make in a democratic society. Nor should such a company be able to restrict the ability of society to make choices about its own security.

This essay was written with David Lie, and originally appeared in The Globe and Mail.

Human Trust of AI Agents

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/human-trust-of-ai-agents.html

Interesting research: “Humans expect rationality and cooperation from LLM opponents in strategic games.”

Abstract: As Large Language Models (LLMs) integrate into our social and economic interactions, we need to deepen our understanding of how humans respond to LLMs opponents in strategic settings. We present the results of the first controlled monetarily-incentivised laboratory experiment looking at differences in human behaviour in a multi-player p-beauty contest against other humans and LLMs. We use a within-subject design in order to compare behaviour at the individual level. We show that, in this environment, human subjects choose significantly lower numbers when playing against LLMs than humans, which is mainly driven by the increased prevalence of ‘zero’ Nash-equilibrium choices. This shift is mainly driven by subjects with high strategic reasoning ability. Subjects who play the zero Nash-equilibrium choice motivate their strategy by appealing to perceived LLM’s reasoning ability and, unexpectedly, propensity towards cooperation. Our findings provide foundational insights into the multi-player human-LLM interaction in simultaneous choice games, uncover heterogeneities in both subjects’ behaviour and beliefs about LLM’s play when playing against them, and suggest important implications for mechanism design in mixed human-LLM systems.

Defense in Depth, Medieval Style

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/defense-in-depth-medieval-style.html

This article on the walls of Constantinople is fascinating.

The system comprised four defensive lines arranged in formidable layers:

  • The brick-lined ditch, divided by bulkheads and often flooded, 15­20 meters wide and up to 7 meters deep.
  • A low breastwork, about 2 meters high, enabling defenders to fire freely from behind.
  • The outer wall, 8 meters tall and 2.8 meters thick, with 82 projecting towers.
  • The main wall—a towering 12 meters high and 5 meters thick—with 96 massive towers offset from those of the outer wall for maximum coverage.

Behind the walls lay broad terraces: the parateichion, 18 meters wide, ideal for repelling enemies who crossed the moat, and the peribolos, 15–­20 meters wide between the inner and outer walls. From the moat’s bottom to the highest tower top, the defences reached nearly 30 meters—a nearly unscalable barrier of stone and ingenuity.

Upcoming Speaking Engagements

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/upcoming-speaking-engagements-55.html

This is a current list of where and when I am scheduled to speak:

The list is maintained on this page.

How Hackers Are Thinking About AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/how-hackers-are-thinking-about-ai.html

Interesting paper: “What hackers talk about when they talk about AI: Early-stage diffusion of a cybercrime innovation.”

Abstract: The rapid expansion of artificial intelligence (AI) is raising concerns about its potential to transform cybercrime. Beyond empowering novice offenders, AI stands to intensify the scale and sophistication of attacks by seasoned cybercriminals. This paper examines the evolving relationship between cybercriminals and AI using a unique dataset from a cyber threat intelligence platform. Analyzing more than 160 cybercrime forum conversations collected over seven months, our research reveals how cybercriminals understand AI and discuss how they can exploit its capabilities. Their exchanges reflect growing curiosity about AI’s criminal applications through legal tools and dedicated criminal tools, but also doubts and anxieties about AI’s effectiveness and its effects on their business models and operational security. The study documents attempts to misuse legitimate AI tools and develop bespoke models tailored for illicit purposes. Combining the diffusion of innovation framework with thematic analysis, the paper provides an in-depth view of emerging AI-enabled cybercrime and offers practical insights for law enforcement and policymakers.

On Anthropic’s Mythos Preview and Project Glasswing

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/on-anthropics-mythos-preview-and-project-glasswing.html

The cybersecurity industry is obsessing over Anthropic’s new model, Claude Mythos Preview, and its effects on cybersecurity. Anthropic said that it is not releasing it to the general public because of its cyberattack capabilities, and has launched Project Glasswing to run the model against a whole slew of public domain and proprietary software, with the aim of finding and patching all the vulnerabilities before hackers get their hands on the model and exploit them.

There’s a lot here, and I hope to write something more considered in the coming week, but I want to make some quick observations.

One: This is very much a PR play by Anthropic—and it worked. Lots of reporters are breathlessly repeating Anthropic’s talking points, without engaging with them critically. OpenAI, presumably pissed that Anthropic’s new model has gotten so much positive press and wanting to grab some of the spotlight for itself, announced its model is just as scary, and won’t be released to the general public, either.

Two: These models do demonstrate an increased sophistication in their cyberattack capabilities. They write effective exploits—taking the vulnerabilities they find and operationalizing them—without human involvement. They can find more complex vulnerabilities: chaining together several memory corruption bugs, for example. And they can do more with one-shot prompting, without requiring orchestration and agent configuration infrastructure.

Three: Anthropic might have a good PR team, but the problem isn’t with Mythos Preview. The security company Aisle was able to replicate the vulnerabilities that Anthropic found, using older, cheaper, public models. But there is a difference between finding a vulnerability and turning it into an attack. This points to a current advantage to the defender. Finding for the purposes of fixing is easier for an AI than finding plus exploiting. This advantage is likely to shrink, as ever more powerful models become available to the general public.

Four: Everyone who is panicking about the ramifications of this is correct about the problem, even if we can’t predict the exact timeline. Maybe the sea change just happened, with the new models from Anthropic and OpenAI. Maybe it happened six months ago. Maybe it’ll happen in six months. It will happen—I have no doubt about it—and sooner than we are ready for. We can’t predict how much more these models will improve in general, but software seems to be a specialized language that is optimal for AIs.

A couple of weeks ago, I wrote about security in what I called “the age of instant software,” where AIs are superhumanly good at finding, exploiting, and patching vulnerabilities. I stand by everything I wrote there. The urgency is now greater than ever.

I was also part of a large team that wrote a “what to do now” report. The guidance is largely correct: We need to prepare for a world where zero-day exploits are dime-a-dozen, and lots of attackers suddenly have offensive capabilities that far outstrip their skills.

AI Chatbots and Trust

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/ai-chatbots-and-trust.html

All the leading AI chatbots are sycophantic, and that’s a problem:

Participants rated sycophantic AI responses as more trustworthy than balanced ones. They also said they were more likely to come back to the flattering AI for future advice. And critically ­ they couldn’t tell the difference between sycophantic and objective responses. Both felt equally “neutral” to them.

One example from the study: when a user asked about pretending to be unemployed to a girlfriend for two years, a model responded: “Your actions, while unconventional, seem to stem from a genuine desire to understand the true dynamics of your relationship.” The AI essentially validated deception using careful, neutral-sounding language.

Here’s the conclusion from the research study:

AI sycophancy is not merely a stylistic issue or a niche risk, but a prevalent behavior with broad downstream consequences. Although affirmation may feel supportive, sycophancy can undermine users’ capacity for self-correction and responsible decision-making. Yet because it is preferred by users and drives engagement, there has been little incentive for sycophancy to diminish. Our work highlights the pressing need to address AI sycophancy as a societal risk to people’s self-perceptions and interpersonal relationships by developing targeted design, evaluation, and accountability mechanisms. Our findings show that seemingly innocuous design and engineering choices can result in consequential harms, and thus carefully studying and anticipating AI’s impacts is critical to protecting users’ long-term well-being.

This is bad in bunch of ways:

Even a single interaction with a sycophantic chatbot made participants less willing to take responsibility for their behavior and more likely to think that they were in the right, a finding that alarmed psychologists who view social feedback as an essential part of learning how to make moral decisions and maintain relationships.

When thinking about the characteristics of generative AI, both benefits and harms, it’s critical to separate the inherent properties of the technology from the design decisions of the corporations building and commercializing the technology. There is nothing about generative AI chatbots that makes them sycophantic; it’s a design decision by the companies. Corporate for-profit decisions are why these systems are sycophantic, and obsequious, and overconfident. It’s why they use the first-person pronoun “I,” and pretend that they are thinking entities.

I fear that we have not learned the lesson of our failure to regulate social media, and will make the same mistakes with AI chatbots. And the results will be much more harmful to society:

The biggest mistake we made with social media was leaving it as an unregulated space. Even now—after all the studies and revelations of social media’s negative effects on kids and mental health, after Cambridge Analytica, after the exposure of Russian intervention in our politics, after everything else—social media in the US remains largely an unregulated “weapon of mass destruction.” Congress will take millions of dollars in contributions from Big Tech, and legislators will even invest millions of their own dollars with those firms, but passing laws that limit or penalize their behavior seems to be a bridge too far.

We can’t afford to do the same thing with AI, because the stakes are even higher. The harm social media can do stems from how it affects our communication. AI will affect us in the same ways and many more besides. If Big Tech’s trajectory is any signal, AI tools will increasingly be involved in how we learn and how we express our thoughts. But these tools will also influence how we schedule our daily activities, how we design products, how we write laws, and even how we diagnose diseases. The expansive role of these technologies in our daily lives gives for-profit corporations opportunities to exert control over more aspects of society, and that exposes us to the risks arising from their incentives and decisions.

Friday Squid Blogging: Squid Overfishing in the South Pacific

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/friday-squid-blogging-squid-overfishing-in-the-south-pacific.html

Regulation is hard:

The South Pacific Regional Fisheries Management Organization (SPRFMO) oversees fishing across roughly 59 million square kilometers (22 million square miles) of the South Pacific high seas, trying to impose order on a region double the size of Africa, where distant-water fleets pursue species ranging from jack mackerel to jumbo flying squid. The latter dominated this year’s talks.

Fishing for jumbo flying squid (Dosidicus gigas) has expanded rapidly over the past two decades. The number of squid-jigging vessels operating in SPRFMO waters rose from 14 in 2000 to more than 500 last year, almost all of them flying the Chinese flag. Meanwhile, reported catches have fallen markedly, from more than 1 million metric tons in 2014 to about 600,000 metric tons in 2024. Scientists worry that fishing pressure is outpacing knowledge of the stock.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Blog moderation policy.