Using EasyCrypt and Jasmin for post-quantum verification

Post Syndicated from Sofía Celi original https://blog.cloudflare.com/post-quantum-easycrypt-jasmin/
Using EasyCrypt and Jasmin for post-quantum verification

Using EasyCrypt and Jasmin for post-quantum verification

Cryptographic code is everywhere: it gets run when we connect to the bank, when we send messages to our friends, or when we watch cat videos. But, it is not at all easy to take a cryptographic specification written in a natural language and produce running code from it, and it is even harder to validate both the theoretical assumptions and the correctness of the implementation itself. Mathematical proofs, as we talked about in our previous blog post, and code inspection are simply not enough. Testing and fuzzing can catch common or well-known bugs or mistakes, but might miss rare ones that can, nevertheless, be triggered by an attacker. Static analysis can detect mistakes in the code, but cannot check whether the code behaves as described by the specification in natural-language (for functional correctness). This gap between implementation and validation can have grave consequences in terms of security in the real world, and we need to bridge this chasm.

In this blog post, we will be talking about ways to make this gap smaller by making the code we deploy better through analyzing its security properties and its implementation. This blog post continues our work on high assurance cryptography, for example, on using Tamarin to analyze entire protocol specifications. In this one, we want to look more on the side of verifying implementations. Our desire for high assurance cryptography isn’t specific to post-quantum cryptography, but because quantum-safe algorithms and protocols are so new, we want extra reassurance that we’re doing the best we can. The post-quantum era also gives us a great opportunity to try and apply all the lessons we’ve learned while deploying classical cryptography, which will hopefully prevent us from making the same mistakes all over again.

This blog post will discuss formal verification. Formal verification is a technique we can use to prove that a piece of code correctly implements a specification. Formal verification, and formal methods in general, have been around for a long time, appearing as early as the 1950s. Today, they are being applied in a variety of ways: from automating the checking of security proofs to automating checks for functional correctness and the absence of side-channels attacks. Code verified using such formal verification has been deployed in popular products like Mozilla Firefox and Google Chrome.

Formal verification, as opposed to formal analysis, the topic of other blog posts, deals with verifying code and checking that it correctly implements a specification. Formal analysis, on the other hand, deals with establishing that a specification has the desired properties, for example, having a specific security guarantee.

Let’s explore what it means for an algorithm to have a proof that it achieves a certain security goal and what it means to have an implementation we can prove correctly implements that algorithm.

Goals of a formal analysis and verification process

Our goal, given a description of an algorithm in a natural language, is to produce two proofs: first, one that shows that the algorithm has the security properties we want and, second, that we have a correct implementation of it. We can go about this in four steps:

  1. Turn the algorithm and its security goals into a formal specification. This is us defining the problem.
  2. Use formal analysis to prove, in our case using a computer-aided proof tooling, that the algorithm attains the specified properties.
  3. Use formal verification to prove that the implementation correctly implements the algorithm.
  4. Use formal verification to prove that our implementation has additional properties, like memory safety, running in constant time, efficiency, etc.

Interestingly we can do step 2 in parallel with steps 3 and 4, because the two proofs are actually independent. As long as they are both building from the same specification established in step 1, the properties we establish in the formal analysis should flow down to the implementation.

Suppose, more concretely, we’re looking at an implementation and specification of a Key Encapsulation Mechanism (a KEM, such as FrodoKEM). FrodoKEM is designed to achieve IND-CCA security, so we want to prove that it does, and that we have an efficient, side-channel resistant and correct implementation of it.

As you might imagine, achieving even one of these goals is no small feat. Achieving all, especially given the way they conflict (efficiency clashes with side-channel resistance, for example), is a Herculean task. Decades of research have gone into this space, and it is huge; so let’s carve out and examine a small subsection to look at: we’ll look at two tools, EasyCrypt and Jasmin.

Before we jump into the tools, let’s take a brief aside to discuss why we’re not using Tamarin, which we’ve talked about in our other blog posts. Like EasyCrypt, Tamarin is also a tool used for formal analysis, but beyond that, the two tools are quite different. Formal analysis broadly splits into two camps, symbolic analysis and computational analysis. Tamarin, as we saw, uses symbolic analysis, which treats all functions effectively as black boxes, whereas EasyCrypt uses computational analysis. Computational analysis is much closer to how we program, and functions are given specific implementations. This gives computational analysis a much higher “resolution”: we can study properties in much greater detail and, perhaps, with greater ease. This detail, of course, comes at a cost. As functions grow into full protocols, with multiple modes, branching paths, and in the case of the Transport Layer Security (TLS), sometimes even resumption, computational models become unwieldy and difficult to work with, even with computer-assisted tooling. We therefore have to pick the correct tool for the job. When we need maximum assurance, sometimes both computational and symbolic proofs are constructed, with each playing to its strengths and compensating for the other’s drawbacks.

EasyCrypt

EasyCrypt is a proof assistant for cryptographic algorithms and imperative programs. A proof is basically a formal demonstration that some statement is true. EasyCrypt is called a proof assistant because it “assists” you with creating a proof; it does not create a proof for you, but rather, helps you come to it and gives you the power to have a machine check that each step logically follows from the last. It provides a language to write definitions, programs, and theorems along with an environment to develop machine-checked proofs.

A proof starts from a set of assumptions, and by taking a series of logical steps demonstrates that some statement is true. Let’s imagine for a moment that we are the hero Perseus on a quest to kill a mythological being, the terrifying Medusa. How can we prove to everyone that we’ve succeeded? No one is going to want to enter Medusa’s cave to check that she is dead because they’ll be turned to stone. And we cannot just state, “I killed the Medusa.” Who will believe us without proof? After all, is this not a leap of faith?

What we can do is bring the head of the Medusa as proof. Providing the head as a demonstration is our proof because no mortal Gorgon can live without a head. Legend has it that Perseus completed the proof by demonstrating that the head was indeed that of the Medusa: Perseus used the head’s powers to turn Polydectes to stone (the latter was about to force Perseus’ mother to marry him, so let’s just say it wasn’t totally unprovoked). One can say that this proof was done “by hand” in that it was done without any mechanical help. For computer security proofs, sometimes the statements we want to prove are so cumberstone to prove and are so big that having a machine to help us is needed.

How does EasyCrypt achieve this? How does it help you? As we are dealing with cryptography here, first, let’s start by defining how one can reason about cryptography, the security it provides, and the proofs one uses to corroborate them.

When we encrypt something, we do this to hide whatever we want to send. In a perfect world, it would be indistinguishable from noise. Unfortunately, only the one-time-pad truly offers this property, so most of the time we make do with “close enough”: it should be infeasible to differentiate a true encrypted value from a random one.

When we want to show that a certain cryptographic protocol or algorithm has this property, we write it down as an “indistinguishability game.” The idea of the game is as follows:

Imagine a gnome is sitting in a box. The gnome takes a message as input to the box and produces a ciphertext. The gnome records each message and the ciphertext they see generated. A troll outside the box chooses two messages (m1 and m2) of the same length and sends them to the box. The gnome records the box operations and flips a coin. If the coin lands on its face, then the gnome sends the ciphertext (c1) corresponding to m1. Otherwise, they send c2 corresponding to m2. In order to win, the troll, knowing the messages and the ciphertext, has to guess which message was encrypted.

In this example, we can see two things: first, choices are random as the ciphertext sent is chosen by flipping a coin; second, the goal of the adversary is to win a game.

EasyCrypt takes this approach. Security goals are modeled as probabilistic programs (basically, as games) played by an adversary. Tools from program verification and programming language theory are used to justify the cryptographic reasoning. EasyCrypt relies on a “goal directed proof” approach, in which two important mechanisms occur: lemmas and tactics. Let’s see how this approach works (following this amazing paper):

  1. The prover (in this case, you) enters a small statement to prove. For this, one uses the command lemma (meaning this is a minor statement needed to be proven).
  2. EasyCrypt will display the formula as a statement to be proved (i.e the goal) and will also display all the known hypotheses (unproven lemmas) at any given point.
  3. The prover enters a command (a tactic) to either decompose the statement into simpler ones, apply a hypothesis, or make progress in the proof in some other way.
  4. EasyCrypt displays a new set of hypotheses and the parts that still need to be proved.
  5. Back to step 3.

Let’s say you want to prove something small, like the statement “if p in conjunction with q, then q in conjunction with p.” In predicate logic terms, this will be written as (p ∧ q) → (q ∧ p). If we translate this into English statements, as Alice will say in Alice in Wonderland, it could be:

p: I have a world of my own.
q: Everything is nonsense.
p∧q: I have a world of my own and everything is nonsense.
(p ∧ q) → (q ∧ p): If I have a world of my own and everything is nonsense, then, everything is nonsense, and I have a world of my own.

We will walk through such a statement and its proof in EasyCrypt. For more of these examples, see these given by the marvelous Alley Stoughton.
Using EasyCrypt and Jasmin for post-quantum verification
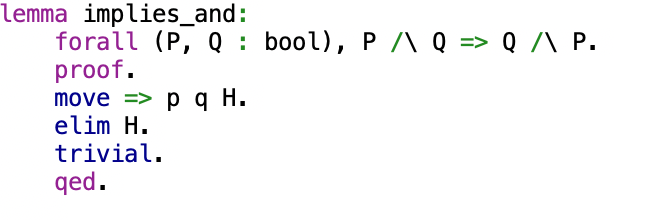
Our lemma and proof in EasyCrypt.

lemma implies_and () :

This line introduces the stated lemma and creatively calls it “implies_and”. It takes no parameters.

(forall (P, Q: bool) => P /\ Q => Q /\ P.

This is the statement we want to prove. We use the variables P and Q of type bool (booleans), and we state that if P and Q, then Q and P.

Up until now we have just declared our statement to prove to EasyCrypt. Let’s see how we write the proof:

proof.
This line demarcates the start of the proof for EasyCrypt.


move => p q H.
We introduce the hypothesis we want to prove (we move them to the “context”). We state that P and Q are both booleans, and that H is the hypothesis P /\ Q.


elim H.

We eliminate H (the conjunctive hypothesis) and we get the components: “p => q => q /\ p”.

trivial.

The proof is now trivial.

qed.

Quod erat demonstrandum (QED) denotes the end of the proof (if both are true, then the conjunction holds). Whew! For such a simple statement, this took quite a bit of work, because EasyCrypt leaves no stone unturned. If you get to this point, you can be sure your proof is absolutely correct, unless there is a bug in EasyCrypt itself (or unless we are proving something that we weren’t supposed to).

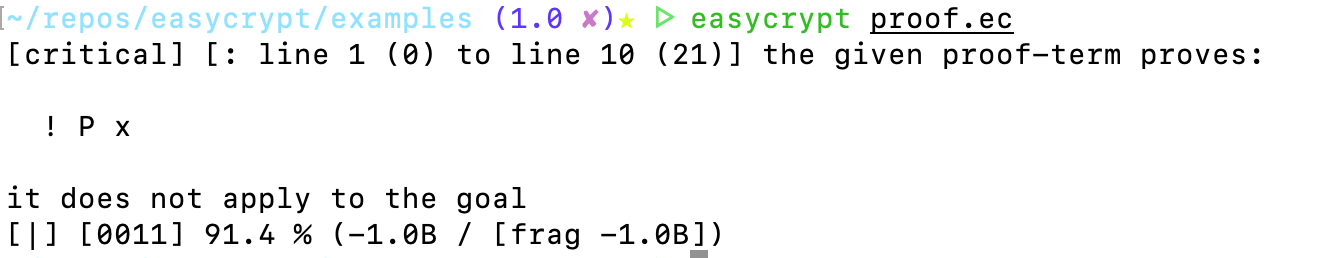
As you see, EasyCrypt helped us by guiding us in decomposing the statement into simpler terms, and stating what still needed to be proven. And by strictly following logical principles, we managed to realize a proof. If we are doing something wrong, and our proof is incorrect, EasyCrypt will let us know, saying something like:
Using EasyCrypt and Jasmin for post-quantum verification
Screenshot of EasyCrypt showing us that we did something wrong.

What we have achieved is a computer-checked proof of the statement, giving us far greater confidence in the proof than if we had to scan over one written with pen and paper. But what makes EasyCrypt particularly attractive in addition to this is its tight integration with the Jasmin programming language as we will see later.

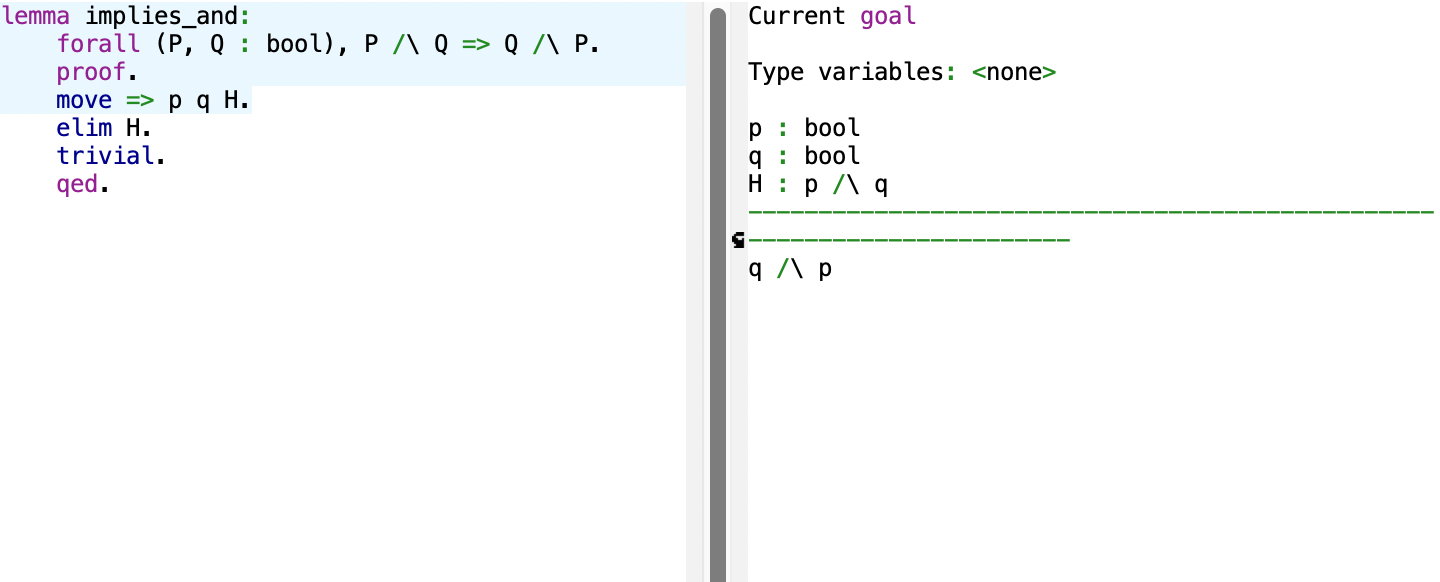
EasyCrypt will also interactively guide us to the proof, as it easily works with ProofGeneral in Emacs. In the image below we see, for example, that EasyCrypt is guiding us by showing the variables we have declared (p, q, and H) and what is missing to be proven (after the dashed line).
Using EasyCrypt and Jasmin for post-quantum verification
EasyCrypt interactively showing us at which point of the proof we are at: the cyan section shows us up until which point we have arrived.

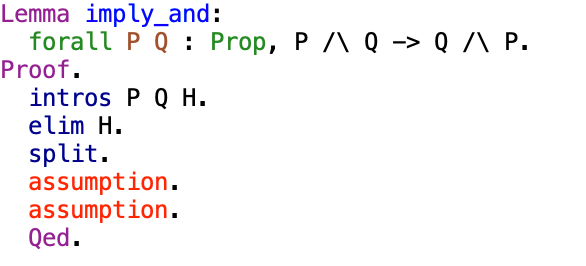
If one is more comfortable with Coq proof assistant (you can find very good tutorials of it), a similar proof can be given:
Using EasyCrypt and Jasmin for post-quantum verification
Our lemma and proof in Coq.

EasyCrypt allows us to prove statements in a faster and more assured manner than if we do proofs by hand. Proving the truthness of the statement we just showed would be easy with the usage of truth tables, for example. But, it is only easy to find these truth tables or proofs when the statement is small. If one is given a complex cryptography algorithm or protocol, the situation is much harder.

Jasmin

Jasmin is an assembly-like programming language with some high-level syntactic conveniences such as loops and procedure calls while using assembly-level instructions. It does support function calls and functional arrays, as well. The Jasmin compiler predictably transforms source code into assembly code for a chosen platform (currently only x64 is supported). This transformation is verified: the correctness of some compiler passes (like function inlining or loop unrolling) are proven and verified in the Coq proof assistant. Other passes are programmed in a conventional programming language and the results are validated in Coq. The compiler also comes with a built-in checker for memory safety and constant-time safety.

This assembly-like syntax, combined with the stated assurances of the compiler, means that we have deep control over the output, and we can optimize it however we like without compromising safety. Because low-level cryptographic code tends to be concise and non-branching, Jasmin doesn’t need full support for general purpose language features or to provide lots of libraries. It only needs to support a set of basic features to give us everything we need.

One reason Jasmin is so powerful is that it provides a way to formally verify low-level code. The other reason is that Jasmin code can be automatically converted by the compiler into equivalent EasyCrypt code, which lets us reason about its security. In general terms, whatever guarantees apply to the EasyCrypt code also flow into the Jasmin code, and subsequently into the assembly code.

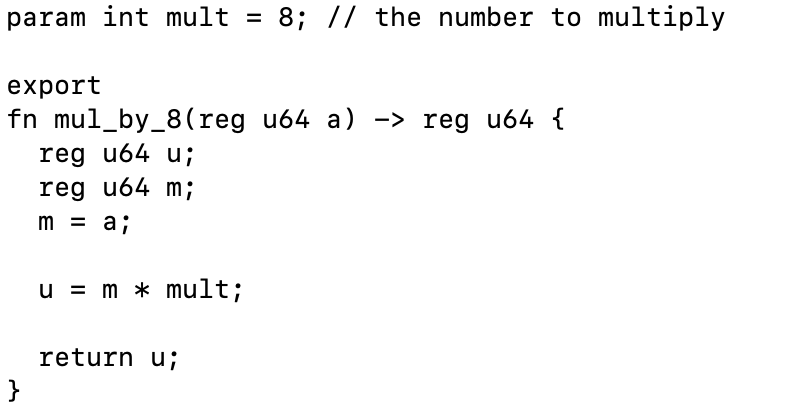
Let’s use the example of a very simple Jasmin function that performs multiplication to see Jasmin in action:
Using EasyCrypt and Jasmin for post-quantum verification
A multiplication function written in Jasmin.

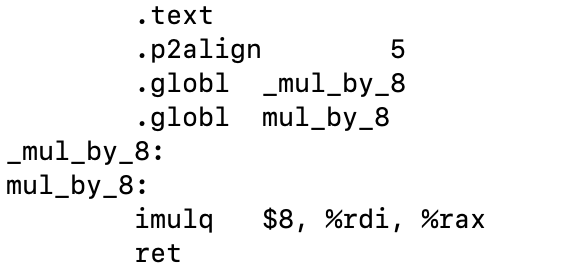
What the function (“fn”) “mul” does, in this case, is to multiply by whatever number is provided as an argument to the function (the variable a). The syntax of this small function should feel very familiar to anyone that has worked with the C family of programming languages. The only big difference is the use of the words reg and u64. What they state is that the variable a, for example, is allocated in registers (hence, the use of reg: this defines the storage of the variable) and that it is 64-bit machine-word (hence, the use of u64). We can convert now this to “pure” x64 assembly:
Using EasyCrypt and Jasmin for post-quantum verification
A multiplication function written in Jasmin and transformed to Assembly.

The first lines of the assembly code are just “setting all up”. They are then followed by the “imulq” instruction, which just multiplies the variable by the constant (which in this case is labeled as “param”). While this small function might not show the full power of having the ability of safely translating to assembly, it can be seen when more complex functions are created. Functions that use while loops, arrays, calls to other functions are accepted by Jasmin and will be safely translated to assembly.

Assembly language has a little bit of a bad reputation because it is thought to be hard to learn, hard to read, and hard to maintain. Having a tool that helps you with translation is very useful to a programmer, and it is also useful as you can manually or automatically check what the assembly code looks like.

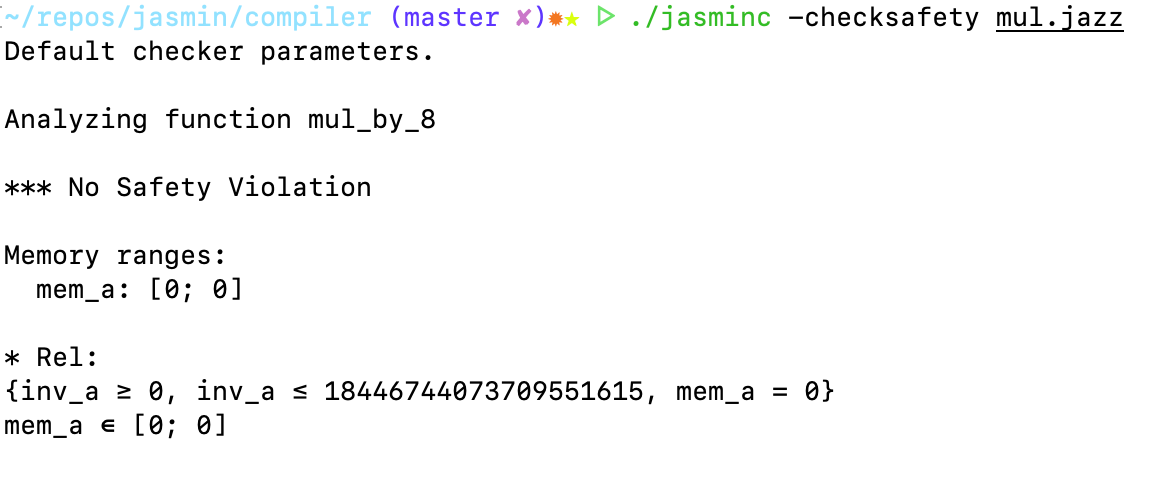
We can further check the code for its safety:
Using EasyCrypt and Jasmin for post-quantum verification
A multiplication function written and checked in Jasmin.

In this check, there are many things to understand. First, it checks that the inputs are allocated in a memory region of at least 0 bytes. Second, the “Rel” entry checks the allocated memory region safety pre-condition: for example, n must point to an allocated memory region of sufficient length.

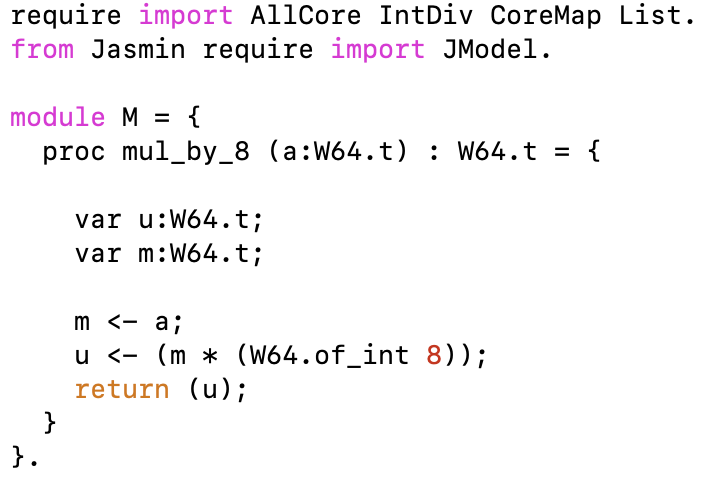
You can then extract this functionality to EasyCrypt (and even configure EasyCrypt to verify Jasmin programs). Here is the corresponding EasyCrypt code, automatically produced by the Jasmin compiler:
Using EasyCrypt and Jasmin for post-quantum verification
A multiplication function written in Jasmin and extracted to EasyCrypt.

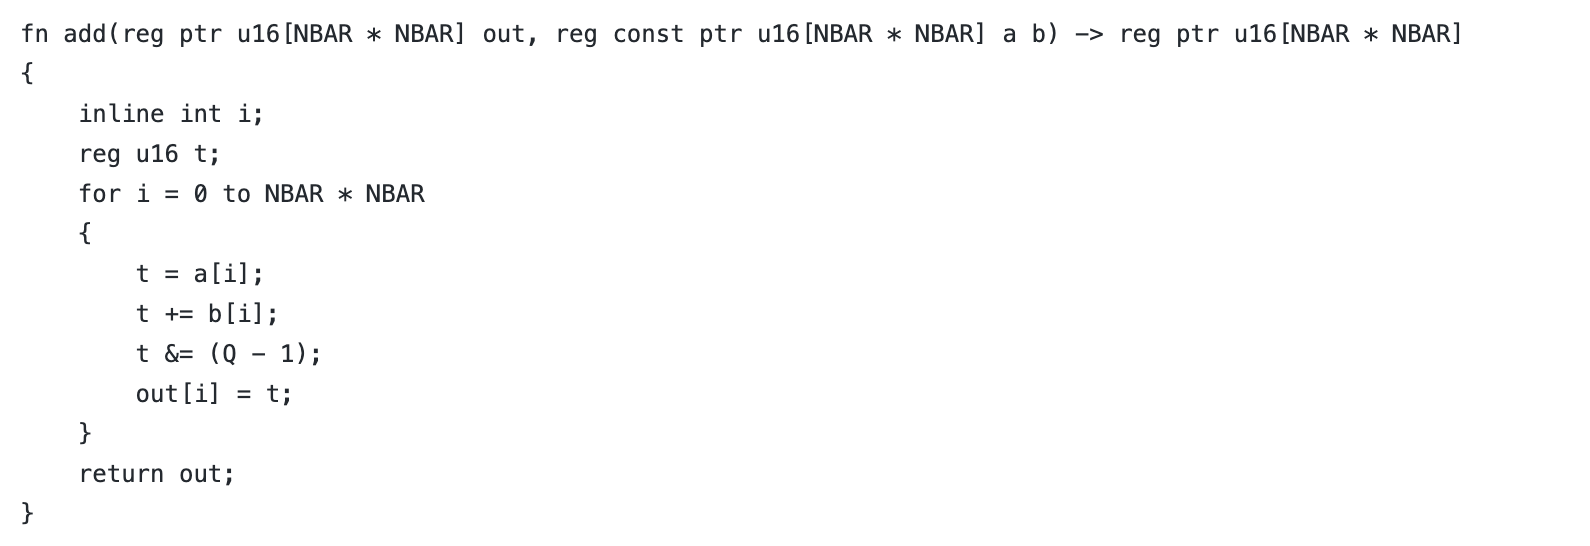
Here’s a slightly more involved example, that of a FrodoKEM utility function written in Jasmin.
Using EasyCrypt and Jasmin for post-quantum verification
A utility function for addition for FrodoKEM.

With a C-like syntax,  this function adds two arrays (a and b), and returns the result (in out). The value NBAR is just a parameter you can specify in a C-like manner. You can then take this function and compile it to assembly. You can also use the Jasmin compiler to analyze the safety of the code (for example, that array accesses are in bounds, that memory accesses are valid, that arithmetic operations are applied to valid arguments) and verify the code runs in constant-time.

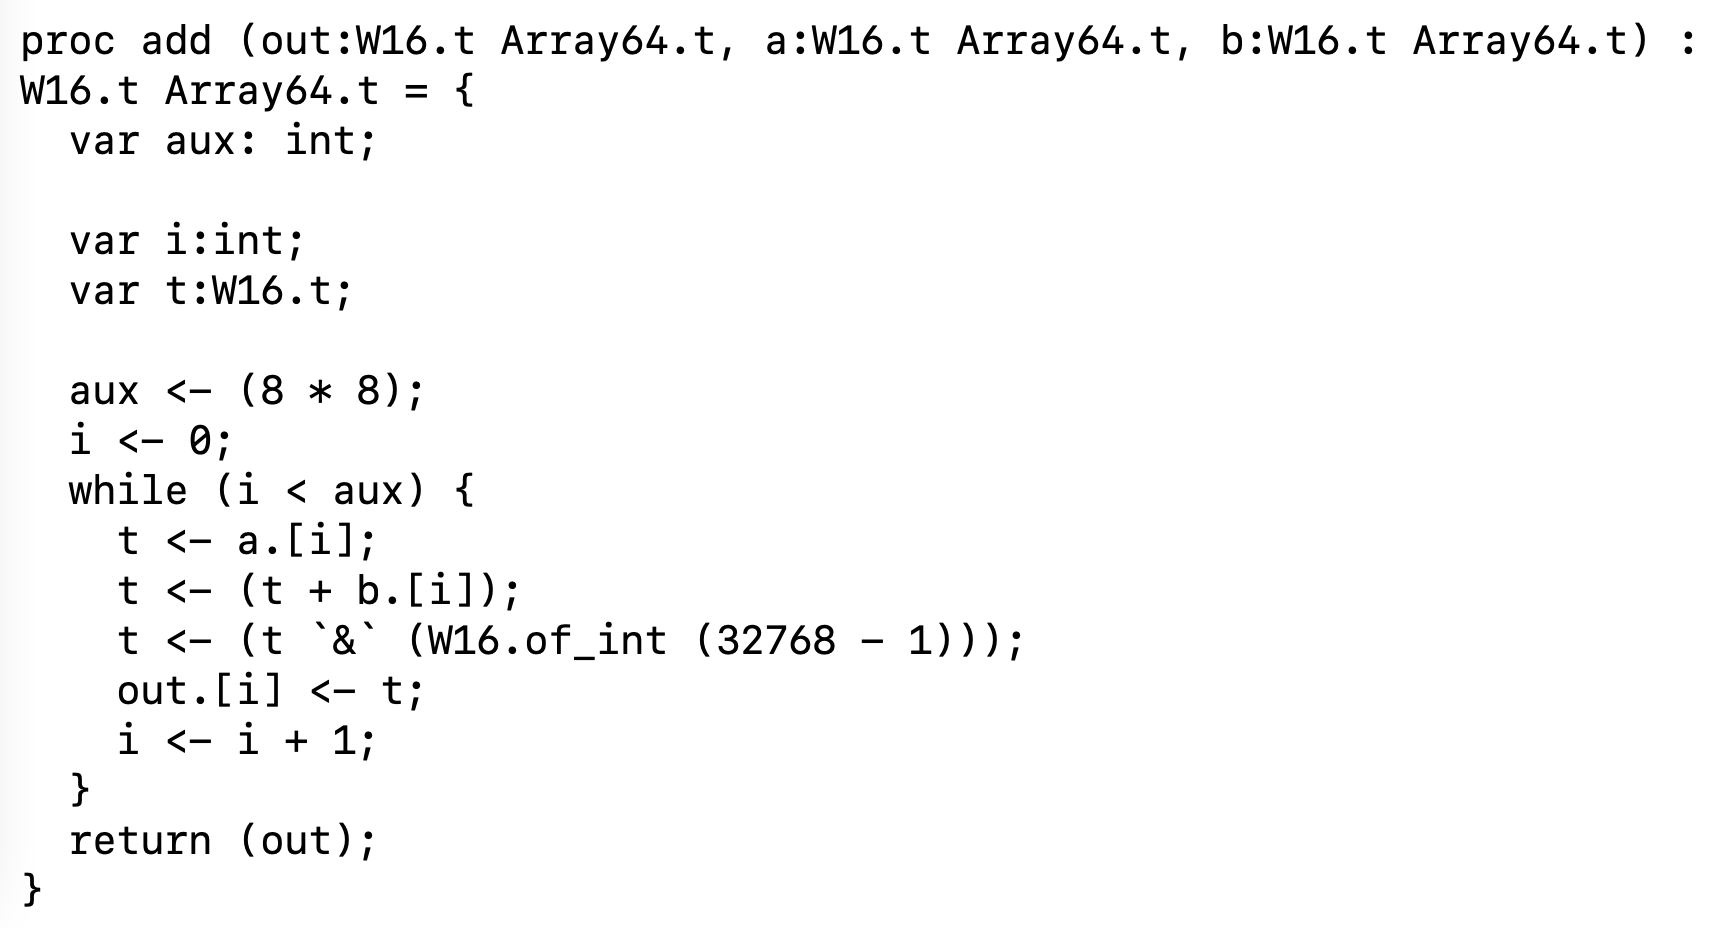
The addition function as used by FrodoKEM can also be extracted to EasyCrypt:
Using EasyCrypt and Jasmin for post-quantum verification
The addition function as extracted to EasyCrypt.

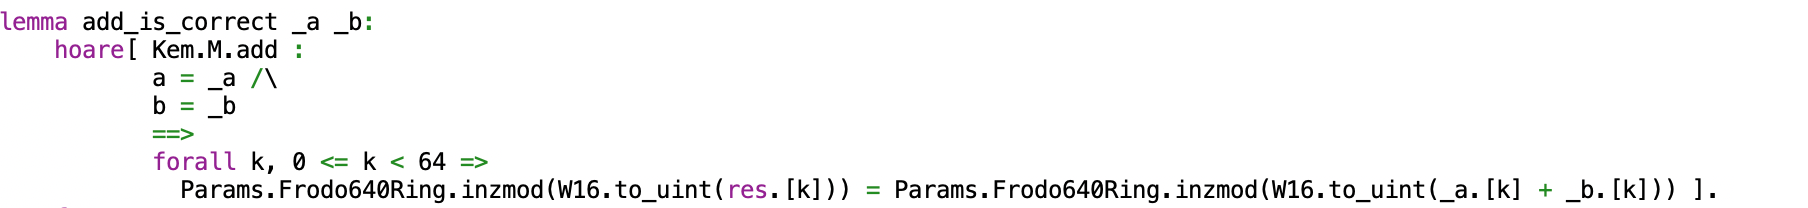
A theorem expressing the correctness (meaning that addition is correct) is expressed in EasyCrypt as so:
Using EasyCrypt and Jasmin for post-quantum verification
The theorem of addition function as extracted to EasyCrypt.

Note that EasyCrypt uses While Language and Hoare Logic. The corresponding proof that states that addition is correct:
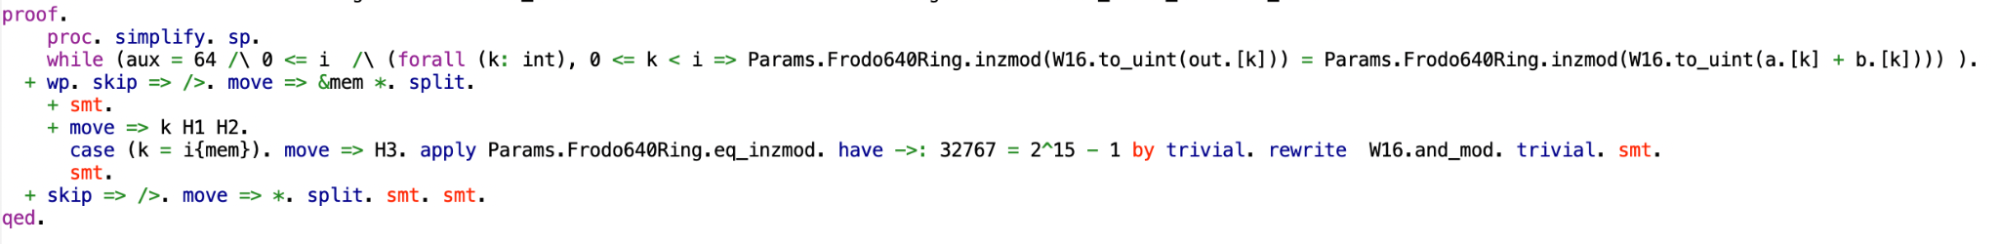
Using EasyCrypt and Jasmin for post-quantum verification
The proof of the addition function as extracted to EasyCrypt.

Why formal verification for post-quantum cryptography?

As we have previously stated, cryptographic implementations are very hard to get right, and even if they are right, the security properties they claim to provide are sometimes wrong for their intended application. The reason why this matters so much is that post-quantum cryptography is the cryptography we will be using in the future due to the arrival of quantum computers. Deploying post-quantum cryptographic algorithms with bugs or flaws in their security properties would be a disaster because connections and data that travels through it can be decrypted or attacked. We are trying to prevent that.

Cryptography is difficult to get right, and it is not only difficult to get right by people new to it, but it is also difficult for anyone, even for the experts. The designs and code we write are error-prone as we all are, as humans, prone to errors. Some examples of when some designs got it wrong are as follows (luckily, these example  were not deployed, and they did not have the usual disastrous consequences):

  • Falcon (a post-quantum algorithm currently part of the NIST procedure), produced valid signatures “but leaked information on the private key,” according to an official comment posted to the NIST post-quantum process on the algorithm. The comment also noted that “the fact that these bugs existed in the first place shows that the traditional development methodology (i.e. “being super careful”) has failed.“
  • “The De Feo–Jao–Plût identification scheme (the basis for SIDH signatures) contains an invalid assumption and provide[s] a counterexample for this assumption: thus showing the proof of soundness is invalid,” according to a finding that one proof of a post-quantum algorithm was not valid. This is an example of an incorrect proof, whose flaws were discovered and eliminated prior to any deployment.

Perhaps these two examples might convince the reader that formal analysis and formal verification of implementations are needed. While they help us avoid some human errors, they are not perfect. As for us, we are convinced of these methods. We are working towards a formally verified implementation of FrodoKEM (we have a first implementation of it in our cryptographic library, CIRCL), and we are collaborating to create a formally verified and implemented library we can run in real-world connections. If you are interested in learning more about EasyCrypt and Jasmin, visit the resources we have put together, try to install it following our guidelines, or follow some tutorials.

See you on other adventures in post-quantum (and some cat videos for you)!

References:

  • “SoK: Computer-Aided Cryptography” by Manuel Barbosa, Gilles Barthe, Karthik Bhargavan, Bruno Blanchet, Cas Cremers, Kevin Liao and Bryan Parno: https://eprint.iacr.org/2019/1393.pdf
  • “EasyPQC: Verifying Post-Quantum Cryptography” by Manuel Barbosa, Gilles Barthe, Xiong Fan, Benjamin Grégoire, Shih-Han Hung, Jonathan Katz, Pierre-Yves Strub, Xiaodi Wu and Li Zhou: https://eprint.iacr.org/2021/1253
  • “Jasmin: High-Assurance and High-Speed Cryptography” by José Bacelar Almeida, Manuel Barbosa, Gilles Barthe, Arthur Blot, Benjamin Grégoire, Vincent Laporte, Tiago Oliveira, Hugo Pacheco, Benedikt Schmidt and Pierre-Yves Strub: https://dl.acm.org/doi/pdf/10.1145/3133956.3134078
  • “The Last Mile: High-Assurance and High-Speed Cryptographic Implementations” by José Bacelar Almeida, Manuel Barbosa, Gilles Barthe, Benjamin Grégoire, Adrien Koutsos, Vincent Laporte,Tiago Oliveira and Pierre-Yves Strub: https://arxiv.org/pdf/1904.04606.pdf
Demystifying XDR: How Curated Detections Filter Out the Noise

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/02/24/demystifying-xdr-how-curated-detections-filter-out-the-noise/

Demystifying XDR: How Curated Detections Filter Out the Noise

Extended detection and response (XDR) is, by nature, a forward-looking technology. By adding automation to human insight, XDR rethinks and redefines the work that has been traditionally ascribed to security information and event management (SIEM) and other well-defined, widely used tools within security teams. For now, XDR can work alongside SIEM — but eventually, it may replace SIEM, once some of XDR’s still-nascent use cases are fully realized.

But what about the pain points that security operations center (SOC) analysts already know so well and feel so acutely? How can XDR help alleviate those headaches right now and make analysts’ lives easier today?

Fighting false positives with XDR

One of the major pain points that Sam Adams, Rapid7’s VP for Detection and Response, brought to light in his recent conversation with Forrester Analyst Allie Mellen, is one that any SOC analyst is sure to know all too well: false positives. Not only does this create noise in the system, Sam pointed out, but it also generates unnecessary work and other downstream effects from the effort needed to untangle the web of confusion. To add to the frustration, you might have missed real alerts and precious opportunities to fight legitimate threats while you were spending time, energy, and money chasing down a false positive.

If, as Sam insisted, every alert is a burden, the burdens your team is bearing better be the ones that matter.

Allie offered a potential model for efficiency in the face of a noisy system: managed detection and response (MDR) providers.

“MDR providers are one of these groups that I get a lot of inspiration from when thinking about what an internal SOC should look like,” she said. While an in-house SOC might not lose money to the same extent an MDR vendor would when chasing down a false positive, they would certainly lose time — a precious resource among often-understaffed and thinly stretched security teams.


Demystifying XDR: How Curated Detections Filter Out the Noise

Got intel?

One of the things that MDR providers do well is threat intelligence — without the right intel feed, they’d be inundated with far too much noise. Sam noted that XDR and SIEM vendors like Rapid7 realize this, too — that’s why we acquired IntSights to deepen the threat intel capabilities of our security platform.

For Allie, the key is to operationalize threat intelligence to ensure it’s relevant to your unique detection and response needs.

“It is definitely not a good idea to just hook up a threat intel feed and hope for the best,” she said. The key is to keep up with the changing threat landscape and to stay ahead of bad actors rather than playing catch-up.

With XDR, curation is the cure

Of course, staying on top of shifting threat dynamics takes time — and it’s not as if analysts don’t already have enough on their plate. This is where XDR comes in. By bringing in a wide range of sources of telemetry, it helps SOC analysts bring together the many balls they’re juggling today so they can accomplish their tasks as effectively as possible.

Allie noted that curated detections have emerged as a key feature in XDR. If you can create detections that are as targeted as possible, this lowers the likelihood of false positives and reduces the amount of time security teams have to spend getting to the bottom of alerts that don’t turn out to be meaningful. Sam pointed out that one of the key ways to achieve this goal is to build detections that focus not on static indicators but on specific behaviors, which are less likely to change dramatically over time.

“Every piece of ransomware is going to try to delete the shadow copy on Windows,” he said, “so it doesn’t matter what the latest version of ransomware is out there – if it’s going to do these three things, we’re going to see it every time.”

Focusing on the patterns that matter in threats helps keep noise low and efficiency high. By putting targeted detections in security analysts’ hands, XDR can alleviate some of their stresses of false positives today and pave the way for the SOC to get even more honed-in in the future.

Want more XDR insights from our conversation with Allie? Check out the full talk.

Additional reading:

[$] Moving the kernel to modern C

Post Syndicated from original https://lwn.net/Articles/885941/

Despite its generally fast-moving nature, the kernel project relies on a
number of old tools. While critics like to focus on the community’s
extensive use of email, a possibly more significant anachronism is the use
of the 1989 version of the C language standard for kernel code — a standard
that was codified before the kernel project even began over 30 years ago.
It is looking like that longstanding practice could be coming to an end as
soon as the 5.18 kernel, which can be expected in May of this year.

Rust compiler ambitions for 2022 (Inside Rust)

Post Syndicated from original https://lwn.net/Articles/885971/

The Inside Rust Blog has posted the
Rust compiler team’s goals
for this year in the hope of encouraging
others to help.

In theory, any unsoundness issue potentially undermines Rust’s
promise of reliability. We want, by the end of this year, to have a
clear understanding of how each of those I-unsound issues came to
be. We are looking into systematically detecting such issues and
whether we can deploy mitigations or fixes for entire classes of
issues, instead of addressing them on a case by case basis.

Security updates for Thursday

Post Syndicated from original https://lwn.net/Articles/885997/

Security updates have been issued by Debian (thunderbird), Fedora (php), openSUSE (jasper and thunderbird), Oracle (389-ds-base, kernel, openldap, and python-pillow), Red Hat (cyrus-sasl and samba), and SUSE (cyrus-sasl, firefox, jasper, kernel-rt, nodejs10, nodejs14, nodejs8, and thunderbird).

Computer science education for what purpose? Some perspectives

Post Syndicated from Janina Ander original https://www.raspberrypi.org/blog/computer-science-education-equity-change-purpose/

As we’re coming to the end of Black History Month in the USA this year, we’ve been amazed by the variety of work the computing education community is doing to address inequities in their classrooms. For our part, we have learned a huge amount about equitable STEM and computer science (CS) education from the community, and through our own research.

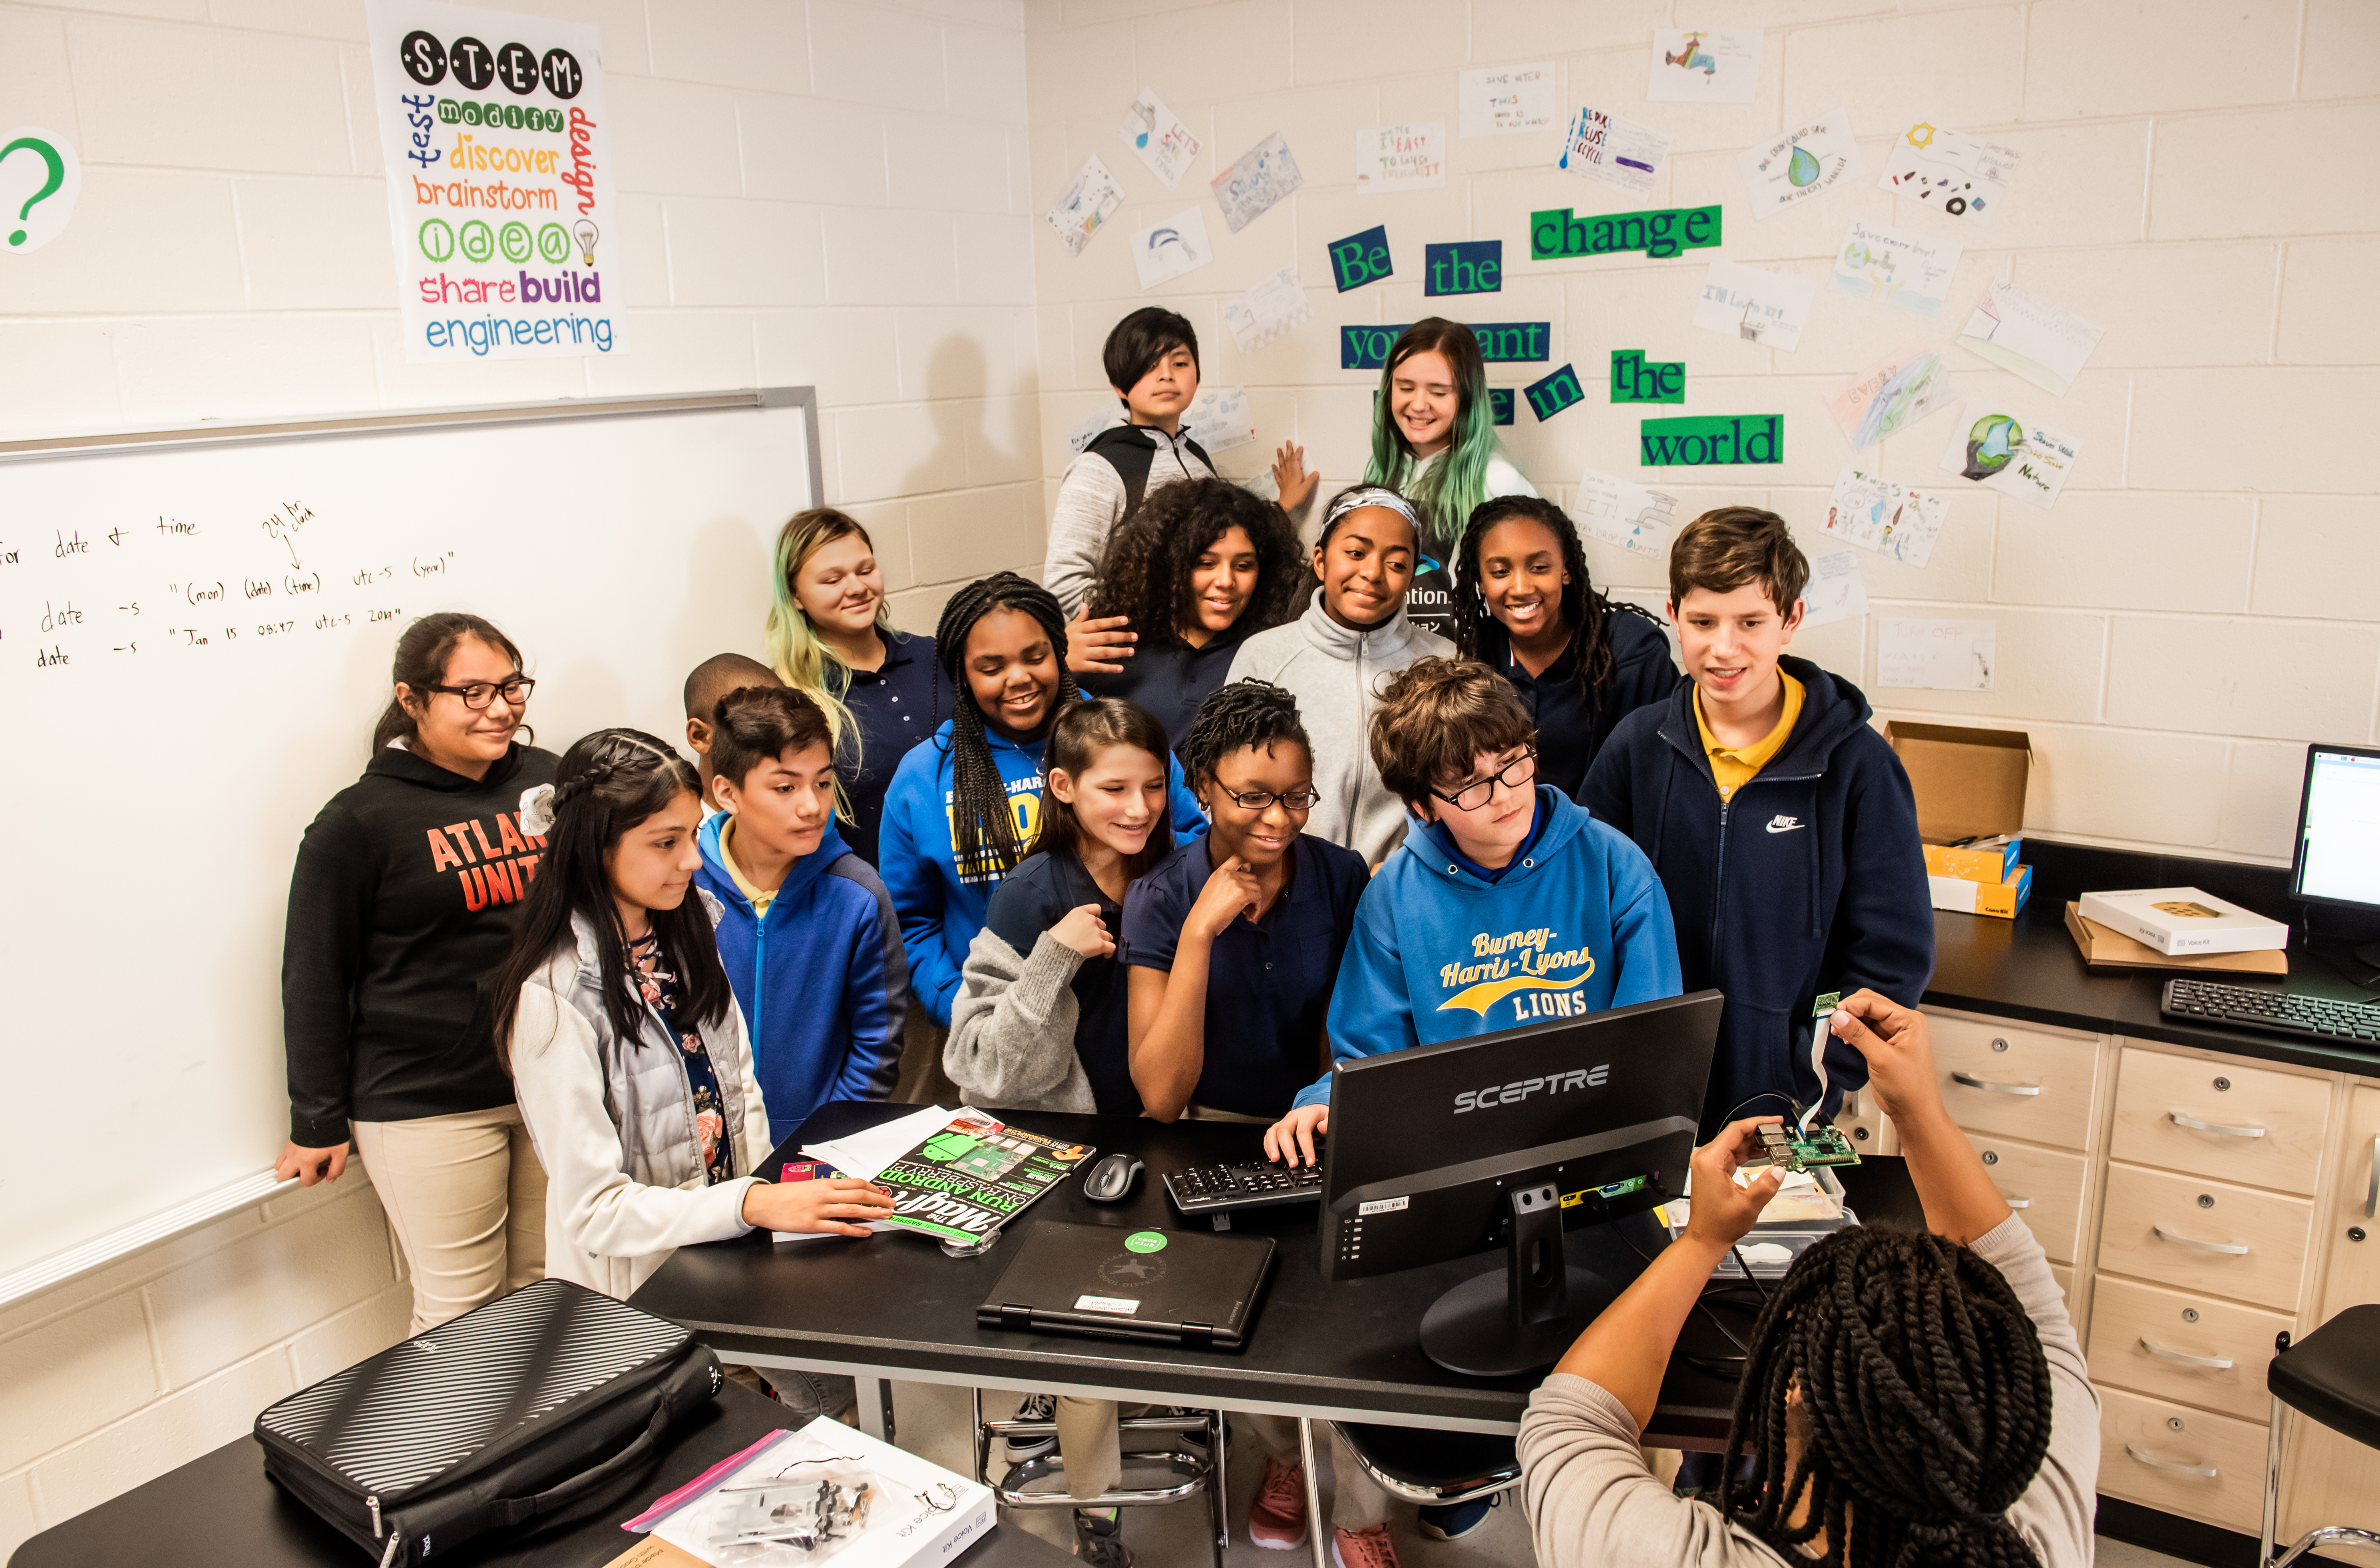
A group of young people in a computer science classroom pose for a group photo.

In this post, we want to highlight two particular pieces of work that have influenced our work over the last year, shared by Dr Tia C. Madkins (University of Texas at Austin), Dr Nicol R. Howard (University of Redlands), and Dr Jakita O. Thomas (Auburn University, blackcomputeHER.org) at our research seminars.

Moving beyond access and achievement, towards equity and justice

Tia C. Madkins and Nicol R. Howard described that educators in schools (and associated professionals) need to build an awareness of how the learning in their classrooms might be affected by:

  • Personal beliefs, ways of knowing or thinking, stereotypes, and the cultural lens of the educator and the learners
  • Power dynamics and intersectional identities

They say: “Instead of viewing learners as deficient individuals who we need to ‘fix’ in our classrooms, we use strengths-based approaches where we as educators learn to recognise, draw on, and build upon learners’ strengths and lived experiences.”

The researchers encourage educators to connect with learners’ cultural practices and lived experiences, and to foster and maintain relationships with learners’ families and communities, in order to work together to facilitate equitable, social justice–oriented CS learning

To hear from Tia, Nicol, and their collaborator Shomari Jones, watch their seminar. You can also read Tia and Nicol’s article in our seminar proceedings, where you’ll find a list of their recommended resources to explore this thinking further.

Valuing existing knowledge and lived experience as expertise

Jakita O. Thomas described findings from her research project based on a free enrichment programme exploring how Black middle-school girls develop computational algorithmic thinking skills in the context of game design.

The programme was intentionally designed to position Black girls as knowledge holders with valuable experiences, and to offer them opportunities to shape their identities as producers, innovators, and people who challenge deficit perspectives. These are perspectives that include implicit assumptions that privilege the values, beliefs, and practices of one group over another, especially where the groups are racially, ethnically, or culturally different.

Jakita emphasised that it’s very important for educators to ask the questions “STEM learning for what?”, “For whom?”, “How?”, and “To what ends?” when they consider how to bring STEM learning experiences to Black girls (or other young people with multiple marginal identities). Educators need an awareness that the economic reasons of STEM learning, which are commonly spotlighted, may not be sufficient to convince young people who are marginalised to engage in these subjects.

To hear more about this from Jakita directly, watch her seminar:

Empowering learners to be agents of change

One thing these researchers’ work makes clear is that the reasons for why learners choose to engage in CS education are many, and that gaining CS skills to prepare for the job market is only one of them.

In both seminars, the speakers emphasised how important it is for educators to contribute to their learners’ self-view as agents of change, not only by demonstrating how CS can be used to solve problems, but also by being open and direct about existing technological inequities. This teaches learners to use CS as a tool, and to also examine the social context in which CS is being applied, and the positive and negative consequences of these applications. Learning CS can empower young people to address challenges their communities face, and educators, learners, and families can work together through CS on social justice issues.

Putting the power of computing into the hands of young people is the core of our mission, and we have a research project underway right now that looks at equitable computing education in UK schools. Find out more about it here, and download our practical guide for teachers.

The post Computer science education for what purpose? Some perspectives appeared first on Raspberry Pi.

An Elaborate Employment Con in the Internet Age

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/02/an-elaborate-employment-con-in-the-internet-age.html

The story is an old one, but the tech gives it a bunch of new twists:

Gemma Brett, a 27-year-old designer from west London, had only been working at Madbird for two weeks when she spotted something strange. Curious about what her commute would be like when the pandemic was over, she searched for the company’s office address. The result looked nothing like the videos on Madbird’s website of a sleek workspace buzzing with creative-types. Instead, Google Street View showed an upmarket block of flats in London’s Kensington.

[…]

Using online reverse image searches they dug deeper. They found that almost all the work Madbird claimed as its own had been stolen from elsewhere on the internet — and that some of the colleagues they’d been messaging online didn’t exist.

[…]

At least six of the most senior employees profiled by Madbird were fake. Their identities stitched together using photos stolen from random corners of the internet and made-up names. They included Madbird’s co-founder, Dave Stanfield — despite him having a LinkedIn profile and Ali referring to him constantly. Some of the duped staff had even received emails from him.

Read the whole sad story. What’s amazing is how shallow all the fakery was, and how quickly it all unraveled once people started digging. But until there’s suspicion enough to dig, we take all of these things at face value. And in COVID times, there’s no face-to-face anything.

Handy Tips #24: Preventing downtimes with The Zabbix HA cluster

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/handy-tips-24-preventing-downtimes-with-the-zabbix-ha-cluster/19712/

Configure automated failover between Zabbix server nodes with the native Zabbix server HA cluster.

Preventing downtimes is as vital for a monitoring solution as it is for any other component of an organization’s IT infrastructure. High availability and automated failover can help you prevent unwanted downtimes by supporting multiple application nodes and failing over between them once a primary node has failed.

Deploy native Zabbix server High availability cluster:

  • Deploy two or more Zabbix server nodes
  • No external tools are required to deploy a Zabbix server HA cluster

  • Define custom failover delay before failing over to another node
  • Monitor the status of your Zabbix cluster on Zabbix dashboards

Check out the video to learn how to deploy the Zabbix server High availability cluster:

How to deploy the Zabbix server High availability cluster:
 
  1. Deploy two or more Zabbix server nodes
  2. On all cluster nodes open the Zabbix server configuration file – zabbix_server.conf
  3. On all cluster nodes provide arbitrary node name in the HANodeName parameter
  4. On both nodes provide the node address in the NodeAddress parameter
  5. Open your Zabbix frontend configuration file – zabbix.conf.php
  6. Comment out the //$ZBX_SERVER and $ZBX_SERVER_PORT parameters
  7. From the active node check the HA cluster status with zabbix_server -R ha_status command
  8. Open your Zabbix frontend GUI
  9. Navigate to Reports →  System information
  10. Confirm the Zabbix server HA cluster node status

Tips and best practices:
  • Specifying the HANodeName parameter in the Zabbix server configuration file enables the HA cluster mode
  • The NodeAddress parameter is used by the Zabbix frontend to connect to the active cluster node
  • Zabbix frontend configuration file parameters – $ZBX_SERVER and $ZBX_SERVER_PORT must be commented out for the frontend to automatically detect the active cluster node
  • The current status of the HA cluster can be managed using the dedicated runtime control options

The post Handy Tips #24: Preventing downtimes with The Zabbix HA cluster appeared first on Zabbix Blog.

„Путин си търсеше повод за война.“ Разговор с Димо Гяуров

Post Syndicated from Венелина Попова original https://toest.bg/dimo-gyaurov-interview/

Димо Гяуров е политик и депутат в 37-мото и 41-вото Народно събрание, генерал-майор и председател на Националната разузнавателна служба в мандата на кабинета на ОДС. В периода 2003–2006 г. е извънреден и пълномощен посланик на България в Унгария. Венелина Попова разговаря с г-н Гяуров за Украинската криза и (не)възможните сценарии за нейното развитие.

Въпреки че интервюто е взето вчера, 23 февруари, преди руската армия да нападне Украйна в ранните часове на днешния ден, анализът и изводите в него не са изгубили своята актуалност.


Как очаквате да се развие украинската криза, след като Владимир Путин призна независимостта на двете сепаратистки републики в Донбас и решението на Съвета на Федерацията руската армия да бъде използвана зад граница?

Този въпрос е изключително труден и съм убеден, че в момента всички световни лидери и големи анализатори си блъскат главите с него. Едва ли имат еднозначен отговор, защото всичко е в ръцете на президента Путин, зависи от неговата воля и дори от моментното му настроение. Аз мисля, че едва ли той би спрял дотук. Възможни са различни опции. Едната е да стигне до административните граници на областите Донецк и Луганск, заявка за което даде вчера (22 февруари – б.р.). Което практически означава, че е склонен да завладее украински територии в размер още толкова, колкото са фактическите граници на двете т.нар. народни републики. Другата опция е да не се задоволи само с това, а да предприеме и някакви действия в Запорожката област с цел да осигури водоснабдяването на Крим и сухопътната му връзка с Русия. Това означава да отреже излаза на Украйна на Азовско море и да стигне чак до Одеса, с което би постигнал и друга стратегическа цел – да си осигури монополно предимство в акваторията на Черно море. Но да се предскажат бъдещите планове на Путин е трудно. Трябва да очакваме всичко.

Да, и от близо едночасовата изнервена реч на руския президент разбрахме, че в неговото съзнание Украйна е без граници. Но възможно ли е в желанието си да превърне краха на дипломацията си в победа, Владимир Путин да повтори в Донбас сценария от Крим? Руският президент знае, че няма кой да му попречи да анексира нови територии от Украйна – или греша?

Да, напълно е възможно. Според мен се повтарят същите вече установени през годините похвати, каквито наблюдавахме и по отношение на Крим, и по отношение на Молдова, и по отношение на Грузия: на базата на поискана помощ Русия влиза с войските си там като „освободител“ и забравя да си тръгне. Много показателно беше поведението на шефа на руското разузнаване по време на заседанието на Съвета за сигурност на Русия. Съжалих го искрено. Човекът беше много объркан и подсъзнателно каза онова, което всички знаем: „Аз съм съгласен областите Донецк и Луганск да бъдат присъединени към Руската федерация.“

А президентът Путин почервеня, засмя се и се опита да заглади гафа с думите, че не става дума за присъединяване на двете народни републики, а само за признаване на тяхната независимост…

Всъщност подсъзнателната реакция на силно смутения шеф на разузнаването показа какви са истинските намерения на Кремъл – завземане на тези територии и тяхното присъединяване към Русия. Практически осем години двете области в Донбас бяха необявена част от федерацията и там Русия действаше подмолно. Сега, с подписаните споразумения, в тях се въвежда рублата, цялата администрация ще функционира на основите на руското законодателство, руски банки ще управляват финансите им, образованието и здравеопазването им ще са по руски модел, а на територията им ще се изградят руски военни бази. Чисто анексиране.

Съгласен ли сте с тезата на украинския политолог Владимир Пастухов, че руската колонизация винаги е имала военно-политически, а не икономически характер и затова често Русия решава свои геополитически проблеми, като поглъща територии по необходимост? Иначе защо Путин би приел да се дискредитира в очите на свободния свят за пореден път, а страната му да понесе тежки санкции, освен за да демонстрира сила, превъзходство и имперско самочувствие?

Склонен съм да приема такава теза, макар че още не мога да си отговоря дали онова, което руският президент изрече онзи ден в обръщението си към света и към собствения си народ, беше един лошо изигран етюд, или наистина вярва в казаното. Защото той изрече твърдения, които не отговарят нито на действителността, нито на историческата истина. После пък „предупреди“ руския народ, че има заплаха на НАТО към Русия и че трябва да се очакват остри удари по руски обекти от страна на Алианса и на САЩ. Това е или много нискокачествена пропаганда, или откровена лудост. Ако Путин наистина си вярва, това донякъде би могло да обясни желанието му за експанзия. Можем да търсим обяснение в евентуален шизофренен страх и стремеж да се обгради със сателитни режими, за какъвто приемаше и този в Украйна преди Майдана, които биха могли да го охраняват и да изиграят ролята на санитарна полоса между Русия и НАТО – това е страхът на диктатора.

Но тези присъединени територии само тежат на Русия, а не носят икономически облаги, затова и може би руският народ не се чувства колонизатор, за разлика от елитите. Но да продължим – намалява ли шансът за успех на мирните преговори след изявлението на Володимир Зеленски, че е възможно прекратяване на дипломатическите отношения с Русия, предвид заплашителния тон на Путин и Сергей Лавров относно държавния суверенитет на Украйна?

Според мен руският президент едностранно прекрати възможността за по-нататъшни дипломатически ходове и сам обяви скъсването на Минските споразумения. Няма как да преговаряш с човек, който действа задкулисно и лъже. В момента, в който Путин е приемал канцлера на Германия и президента на Франция и е разговарял с тях за деескалация на напрежението, той е организирал анексията на областите в Донбас. Иначе как щяха да бъдат подписани толкова бързо договорите с двете самопровъзгласили се народни републики, ако не бяха предварително подготвени и съгласувани? Затова мисля, че оттук нататък няма кой да вярва на руския президент. Времето на обещанията приключи.

Не че преди това някой от световните лидери особено му вярваше. Иначе Джо Байдън нямаше да предупреди, че вместо изтегляне на руските войски от украинската граница, по нея има съсредоточаване на нови бойни части и техника.

В ХХI век сателитите виждат всичко и е много глупаво да лъжеш, че се оттегляш, когато вкарваш в района нови батальони, когато строиш болници, когато попълваш резервите с кръвни продукти. Това е симптом за подготовка на военни действия.

Срещата между американския и руския президент се отлага, съобщиха от Белия дом. Но дори и тя да се състои, реалистично ли Ви изглежда Путин и индоктринираният кремълски елит да склонят на отстъпки от ултимативните си искания към НАТО, да развеят белия флаг и да оттеглят просто така многохилядната армия от украинската граница – с една дума, да си подвият опашката пред света?

Няма как това да се случи. Путин похарчи милиарди през последната година, за да разкарва военни части от единия до другия край на Русия. Затова ще се опита да извлече максимална полза от тези разходи и да се покаже като победител – най-малкото в очите на руския народ. Путин няма да отстъпи от своите искания. Нещо повече: мисля, че тези искания умишлено бяха поставени като неизпълними, защото президентът търсеше casus belli (повод за война) и оправдание за това, което направи. Той несъмнено знае добре, че няма как НАТО и САЩ да отстъпят от демократичните си ценности и базови принципи и да водят преговори за зачеркването им.

Дори да приемем, че е възможно САЩ и съюзниците им да кажат, че влизането на Украйна в НАТО не е на дневен ред, ще приеме ли Алиансът условието на Путин за демилитаризацията на Източна Европа?

Милитаризацията на държавите от Източна Европа е част от руските опорки. Путин говори за бази на НАТО и на Щатите на територията на Източна Европа, говори за разполагането на американски части и нападателни оръжия. Такива просто няма. Има малочислени ограничени формирования с изключително отбранителен характер.

Още след анексията на Крим през пролетта на 2014 г. НАТО планира разполагането на бази на територията на Латвия, Литва, Естония, Румъния и Полша. В Източна Европа има и военна инфраструктура на Алианса.

Военната инфраструктура е национална и натовска инфраструктура, а петте бази в страните от Източна Европа, които посочвате, бяха създадени в отговор на инвазията в Крим. Нито един елемент от тази инфраструктура няма нападателен характер. Няма нападателни оръжия и разположени ракети, нито многобройни части в жива сила. Когато говори за нападателни оръжия, Путин спекулира с разполагането на елементи от противоракетната система на „Иджис“ (в Румъния и Полша), чието единствено предназначение е да отбранява Европа от потенциална ракетна атака. А когато говори за американски части, трябва да уточним, че става дума за няколко хиляди военни в Германия и няколко хиляди в Прибалтика. Те как се съотнасят към стотиците хиляди на украинската граница? Никак! Когато Путин плаши руснаците, че времето за полет на натовските ракети до Москва е няколко минути, нека да кажем, че времето за полет до европейските столици на ракети, които бяха тествани буквално онзи ден на територията на Беларус по границата ѝ с Украйна, е още по-кратко. Говоренето за демилитаризиране на Източна Европа е пропагандно и е по-скоро предназначено за вътрешна употреба. То има за цел да всее страх в руското общество и да обясни дрънкането на оръжия.

Путин знае, че прекрояване на геополитическата карта на света днес предстои. Ще бъде ли заплаха за свободния свят един съюз на Русия с все по-силните във военно и икономическо отношение страни, като Китай, Индия и Бразилия, да речем, който изглежда все по-възможен? И Иран, който през септември м.г. се присъедини към Шанхайската организация за сътрудничество, ръководена от Русия и Китай?

Русия и Китай действително отдавна изграждат съюзнически отношения, включително и военно-технически. Но тезата, че Китай е безрезервен съюзник на Русия, е дълбоко невярна. От години азиатската държава следва собствена политика и си взаимодейства с Русия дотолкова, доколкото това отговаря на неговите интереси – главно на икономическите.

Да, но и отношението на Русия към Китай е симетрично.

Вярно е, но Русия става все по-зависима от Китай в икономически план. Прекомерното задълбочаване на отношенията и изграждането на стратегически съюзи носят риск и за двете страни. Затова не мисля, че отношенията помежду им ще се развиват еднозначно.

Очаквате ли в сегашната ситуация, която е благоприятна за Китай, той да се опита да си върне Тайван?

Не очаквам такова развитие. Нека не подценяваме китайския лидер Си Дзинпин, който е много интелигентен дипломат. Той не би си позволил действия, подобни на тези на руския президент.

Като човек, който е ръководил Националната служба за разузнаване, имате ли опасения за появата на подобни сепаратистки настроения в България и дали службите работят по тази тема?

Няма опасност у нас да се случи това, което стана в източната част на Украйна. Няма база за сепаратизъм. Но в България има насърчавана и платена русофилия, това е всеизвестен факт. Мисля, че българските контраразузнавателни служби са в дълг да изчистят този проблем.

Аз визирам възможност за възникване на сепаратистки настроения сред турско-мюсюлманското малцинство у нас. Свидетели сме как политическото му представителство в парламента неведнъж е използвало етническата карта, когато е в неизгодна позиция.

Не вярвам това да се случи у нас. Някои политици от Турция са изказвали тези, че у нас има изконно техни територии, виждали сме различни карти, на които част от българските земи са в границите на турската държава, но това не е повод за притеснение.

И това Ви се вижда конспиративно?

Не, не ми се вижда конспиративно. Това дори в отделни моменти е било част от политиката на Турция, но ми се струва, че у нас няма почва за поникването на такива политически тези и настроения. Има една политическа сила, която действително се заиграва с етническата карта, но го прави с оглед на постигането на други цели – предимно икономически. И за постигане на финансови изгоди.

Възможно ли е темата за украинската криза да разцепи управляващата коалиция, в която БСП има различна позиция от тази на останалите партии?

Не, не вярвам да се стигне дотам. Досега бяхме свидетели на сравнително еднозначно отношение към случващото се в Украйна. От друга страна, това, че вчера (22 февруари – б.р.) Народното събрание не можа да излезе с обща декларация, е крайно неприятен факт. Той е показателен, че България продължава да бъде „непълен“ член на НАТО и да има клатушкаща се позиция, когато става дума за теми, свързани с Русия.

Заглавна снимка: Стопкадър от интервю с Димо Гяуров по телевизия „Канал 3“

Източник

Friday Squid Blogging: Squid Videos

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/02/friday-squid-blogging-squid-videos.html

Here are six beautiful squid videos. I know nothing more about them.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

EDITED TO ADD (2/25): This post accidentally went live on Wednesday, two days early, and people started adding their comments then. I have changed the posting date to the correct one, which means that the comments existing before that time will appear to have been made before the post. I apologize for the confusion.

Why we are acquiring Area 1

Post Syndicated from John Graham-Cumming original https://blog.cloudflare.com/why-we-are-acquiring-area-1/

Why we are acquiring Area 1

This post is also available in Français and Español.

Why we are acquiring Area 1

Cloudflare’s mission is to help build a better Internet. We’ve invested heavily in building the world’s most powerful cloud network to deliver a faster, safer and more reliable Internet for our users. Today, we’re taking a big step towards enhancing our ability to secure our customers.

Earlier today we announced that Cloudflare has agreed to acquire Area 1 Security. Area 1’s team has built exceptional cloud-native technology to protect businesses from email-based security threats. Cloudflare will integrate Area 1’s technology with our global network to give customers the most complete Zero Trust security platform available.

Why Email Security?

Back at the turn of the century I was involved in the fight against email spam. At the time, before the mass use of cloud-based email, spam was a real scourge. Clogging users’ inboxes, taking excruciatingly long to download, and running up people’s Internet bills. The fight against spam involved two things, one technical and one architectural.

Technically, we figured out how to use machine-learning to successfully differentiate between spam and genuine. And fairly quickly email migrated to being largely cloud-based. But together these changes didn’t kill spam, but they relegated to a box filled with junk that rarely needs to get looked at.

What spam didn’t do, although for a while it looked like it might, was kill email. In fact, email remains incredibly important. And because of its importance it’s a massive vector for threats against businesses and individuals.

And whilst individuals largely moved to cloud-based email many companies still have on-premise email servers. And, much like anything else in the cybersecurity world, email needs best-in-class protection, not just what’s built in with the email provider being used.

When Cloudflare was in its infancy we considered dealing with the email-borne threat problem but opted to concentrate on building defences for networks and the web. Over time, we’ve vastly expanded our protection and our customers are using us to protect the entirety of their Internet-facing world.

Whilst we can protect a mail server from DDoS, for example, using Magic Transit, that’s just one potential way in which email gets attacked. And far more insidious are emails sent into organizations containing scams, malware and other threats. Just as Cloudflare protects applications that use HTTP, we need to protect email at the application and content level.

If you read the press, few weeks go by without reading a news story about how an organization had significant data compromised because an employee fell for a phishing email.

Cyberthreats are entering businesses via email. Area 1 estimates that more than 90% of cyber security damages are the result of just one thing: phishing. Let’s be clear, email is the biggest exposure for any business.

Existing email security solutions aren’t quite cutting it. Historically, companies have addressed email threats by layering legacy box-based products. And layering they are, as around 1 in 7 Fortune 1000 companies use two or more email security solutions1. If you know Cloudflare, you know legacy boxes are not our thing. As businesses continue to move to the cloud, so does email. Gartner estimates 71% of companies use cloud or hybrid cloud email, with Google’s G Suite and Microsoft’s Office 365 being the most common solutions2. While these companies offer built-in protection capabilities for their email products, many companies do not believe they adequately protect users (more on our own experience with these shortfalls later).

Why we are acquiring Area 1

Trying before buying  

Email security is something that has been on our mind for some time.

Last year we rolled out Email Security DNS Wizard, our first email security product. It was designed as a tool to tackle email spoofing and phishing and improve the deliverability of millions of emails. This was just the first step on our email security journey. Bringing Area 1 onboard is the next, and much larger, step in that journey.

As a security company, we are constantly being attacked. We have been using Area 1 for some time to protect our employees from these attackers.

In early 2020, our security team saw an uptick in employee-reported phishing attempts. Our cloud-based email provider had strong spam filtering, but fell short at blocking malicious threats and other advanced attacks. Additionally, our provider only offered controls to cover their native web application, and did not provide sufficient controls to protect their iOS app and alternate methods of accessing email. Clearly, we needed to layer an email security solution on top of their built-in protection capabilities (more on layering later…).

The team looked for four main things in a vendor: the ability to scan email attachments, the ability to analyze suspected malicious links, business email compromise protection, and strong APIs into cloud-native email providers. After testing many vendors, Area 1 became the clear choice to protect our employees. We implemented Area 1’s solution in early 2020, and the results have been fantastic. With Area 1, we’ve been able to proactively identify phishing campaigns and take action against them before they cause damage. We saw a significant and prolonged drop in phishing emails. Not only that, the Area 1 service had little to no impact on email productivity, which means there were minimal false positives distracting our security team.

In fact, Area 1’s technology was so effective at launch, that our CEO reached out to our Chief Security Officer to inquire if our email security was broken. Our CEO hadn’t seen any phishing attempts reported by our employees for many weeks, a rare occurrence. It turns out our employees weren’t reporting any phishing attempts, because Area 1 was catching all phishing attempts before they reached our employee’s inboxes.

The reason Area 1 is able to do a better job than other providers out there is twofold. First, they have built a significant data platform that is able to identify patterns in emails. Where does an email come from? What does it look like? What IP does it come from? Area 1 has been in the email security space for nine years, and they have amassed an incredibly valuable trove of threat intelligence data. In addition, they have used this data to train state-of-the-art machine learning models to act preemptively against threats.

Layers (Email Security + Zero Trust)

Offering a cloud-based email security product makes sense on its own, but our vision for joining Area 1’s technology to Cloudflare is much larger. We are convinced that adding email security to our existing Zero Trust security platform will result in the best protection for our customers.

Why we are acquiring Area 1

Just as Cloudflare had put Area 1 in front of our existing email solution, many companies put two or more layered email protection products together. But layering is hard. Different products have different configuration mechanisms (some might use a UI, others an API, others might not support Terraform etc.), different reporting mechanisms, and incompatibilities that have to be worked around.

SMTP, the underlying email protocol, has been around since 1982 and in the intervening 40 years a lot of protocols have grown around SMTP to make it secure, add spoof protection, verify senders, and more. Getting layered email security products to work well with all those add-on protocols is hard.

And email doesn’t stand alone. The user’s email address is often the same thing as their company log in. It makes sense to bring Zero Trust and email security together.

Why we are acquiring Area 1

As we’ve discussed, email is a major vector for attacks, but it is not the only one. Email security is just one layer of an enterprise defense system. Most businesses have multiple layers of security to protect their employees and their assets. These defense layers reduce the risk that a system gets penetrated by an attacker. Now imagine all these layers were purpose-built to work with each other seamlessly, built into the same software stack, offered by a single vendor and available to you in 250+ locations around the world.

Imagine a world where you can turn on email security to protect you against phishing, but if for some reason an attacker were to get through to an employee’s inbox, you can create a rule to open any unrecognized link in an isolated remote browser with no text input allowed and scan all email attachments for known malware. That is the power of what we hope to achieve by adding Area 1’s technology onto Cloudflare’s Zero Trust security platform.

Bringing email and Zero Trust together opens up a world of possibilities in protecting email and the enterprise.

Shared Intelligence

At Cloudflare, we’re fans of closely knit products that deliver more value together than they do apart. We refer to that internally as 1+1=3. Incorporating Area 1 into our Zero Trust platform will deliver significant value to our customers, but protecting email is just the start.

Area 1 has spent years training their machine learning models with email data to deliver world-class security. Joining email threat data and Cloudflare’s threat data from our global network will give us incredible power to deliver improved security capabilities for our customers across our products.

Why we are acquiring Area 1

Shared vision

Together with the Area 1 team, we will continue to help build the world’s most robust cloud network and Zero Trust security platform.

On a final note, what struck us most about Area 1 is their shared vision for building a better (and more secure) Internet. Their team is smart, transparent, and curious, all traits we value tremendously at Cloudflare. We are convinced that together our teams can deliver tremendous value to our customers.

If you are interested in upcoming email security products, please register your interest here. You can learn more about the acquisition here or in Area 1’s blog.

The acquisition is expected to close early in the second quarter of 2022 and is subject to customary closing conditions. Until the transaction closes, Cloudflare and Area 1 Security remain separate and independent companies.

Why we are acquiring Area 1

…..

1Piper Sandler 1Q2021 Email Security Survey: Market Share
2Gartner, Market Guide for Email Security, 8 September 2020

[$] Moving Python’s bugs to GitHub

Post Syndicated from original https://lwn.net/Articles/885854/

Over the past seven years or so, Python has slowly been moving its
development infrastructure to GitHub; we covered some of the early discussions at the
end of 2014. One piece of that infrastructure, bug tracking, has not been
moved from bugs.python.org, but plans
are underway
to make that happen soon. It is not a simple or
straightforward process to do so, however, so the transition will take up
to a week to complete; there are a number of interesting facets to the
switch, as it entails clearing some technical, and even legal, hurdles.

Enhance resiliency with admission control in Amazon OpenSearch Service (successor to Amazon Elasticsearch Service)

Post Syndicated from Mital Awachat original https://aws.amazon.com/blogs/big-data/enhance-resiliency-with-admission-control-in-amazon-opensearch-service-successor-to-amazon-elasticsearch-service/

OpenSearch is a distributed, open-source search and analytics suite used for a broad set of use cases like real-time application monitoring, log analytics, and website search. Amazon OpenSearch Service (successor to Amazon Elasticsearch Service) is a managed service that makes it easy to secure, deploy, and operate OpenSearch clusters at scale. Amazon OpenSearch Service provides a broad range of cluster configurations to meet your use cases. In 2021, we released automated memory management under Auto-Tune. Auto-Tune is an adaptive resource management system in Amazon OpenSearch Service that continuously monitors incoming workloads and optimizes cluster resources to improve efficiency and performance.

Today, we’re excited to announce the release of admission control for Auto-Tune. Admission control in Amazon OpenSearch Service enhances the overall resiliency of OpenSearch clusters by limiting new incoming requests early, at the REST layer, when a node is stressed. This mechanism prevents potential node failures and cascading effects on the cluster.

Overview of admission control

Admission control acts like a lever to regulate traffic based on cluster state. It does so by allocating tokens for each OpenSearch request, based on predicted resource usage. It releases the tokens when the process is complete. After all the tokens are acquired, any additional requests to the node are throttled with a “too many requests” exception until tokens are available again for request processing. In some cases, an operator can utilize admission control to completely shut down traffic and prevent frequent node drops until a certain condition is met, such as shards being assigned.

Admission control is a gatekeeper for nodes, limiting the number of requests processed to a node based on its current capacity.

Admission control prevents Amazon OpenSearch Service domains from getting overloaded both by steady increases and surges in traffic. It’s resource-aware, so it tunes the cluster based on incoming request cost (content length of request payload), and the point-in-time state of the node (overall Java Virtual Machine (JVM)). This awareness enables real-time, state-based admission control on the node. Admission control for Auto-Tune is available in all AWS Regions on domains running OpenSearch 1.0, or Elasticsearch 6.7 and higher.

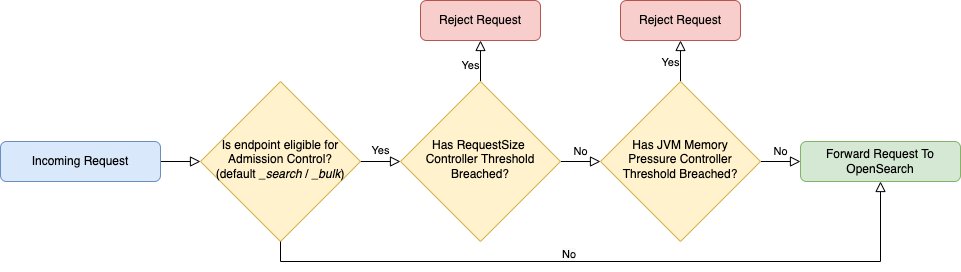
By default, admission control throttles _search and _bulk requests when JVM memory pressure and request size thresholds are breached.

  • JVM memory pressure threshold
    Admission control keeps track of the current state of JVM memory pressure and throttles incoming requests based on a preconfigured JVM memory pressure threshold. When the threshold is breached, all configured _search and _bulk requests are throttled until the memory is released on the node and memory pressure is below the threshold.
  • Request size threshold
    The size of a particular request is determined by it’s content-length. Admission control keeps track of in-flight requests and allocates tokens to every request based on this content length. Admission control then throttles incoming requests based on memory occupancy when the aggregated size of in-flight requests breaches the pre-configured threshold. All new _search and _bulk requests are throttled until the in-flight requests complete, relinquishing the quota to be occupied by new requests.

The following diagram illustrates this process.

How Auto-Tune works

Auto-Tune uses performance and usage metrics from OpenSearch clusters to suggest memory-related configuration changes to improve cluster speed and stability. You can view its recommendations on the Amazon OpenSearch Service console. Admission control is a non-disruptive change, meaning that the changes can be applied without rebooting the node.

Admission control’s predefined request size threshold of 10% satisfies most use cases. However, Auto-Tune can now dynamically increase and decrease the default threshold, typically between 5–15%, based on the amount of JVM that is currently occupied on the system. Request size threshold auto-tuning is enabled by default when you enable Auto-Tune.

Auto-Tune currently doesn’t tune the JVM memory pressure threshold.

Monitoring admission control

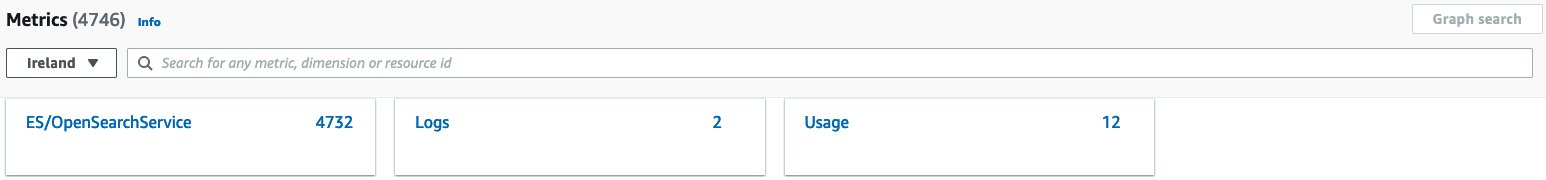
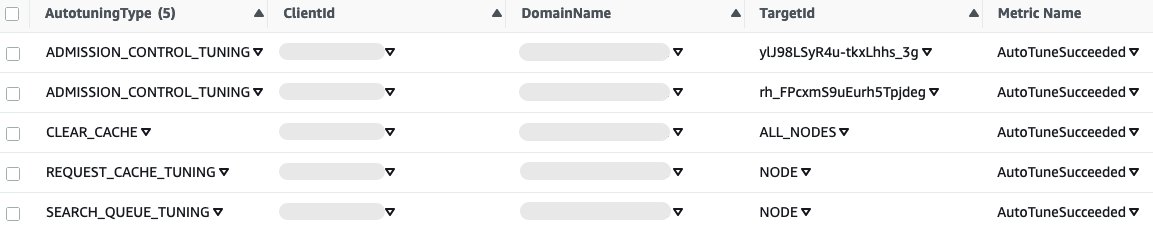
Amazon OpenSearch Service sends two Auto-Tune metrics to Amazon CloudWatch: AutoTuneSucceeded and AutoTuneFailed. Each metric contains a sub-category called AutotuningType, which indicates the specific type of change in question. Admission control adds a new type called ADMISSION_CONTROL_TUNING.

To view it, choose ES/OpenSearchService on the Metrics page on the CloudWatch console.

Then choose AutotuningType, ClientId, DomainName, TargetId.

For AutotuningType, filter by ADMISSION_CONTROL_TUNING.

Conclusion

Admission control introduces request-based rejections of _search and _bulk requests when there are too many requests or JVM usage is high, breaching thresholds. This prevents the nodes from running into cascading effects of failures arising due to the following:

  • Surges in traffic – Sudden surges or spikes in request traffic, leading to quick buildup in usage across the nodes
  • Skew in shard distribution – Improper distribution of shards, leading to hot spots and bottlenecks, affecting the overall performance
  • Slow Nodes – Entire data node starts to slow down due to degraded hardware such as disk, network volumes, or software bugs

Stay tuned for more exciting updates about Amazon OpenSearch Service and features.


About the Authors

Mital Awachat is an SDE-II working on Amazon OpenSearch Service at Amazon Web Services.

Saurabh Singh is a Senior Software Engineer working on AWS OpenSearch at Amazon Web Services. He is passionate about solving problems related to data retrieval and large-scale distributed systems. He is an active contributor to OpenSearch.

Ranjith Ramachandra is an Engineering Manager working on Amazon OpenSearch Service at Amazon Web Services.

Codespaces for the largest repositories just got faster

Post Syndicated from Tanmayee Kamath original https://github.blog/2022-02-23-codespaces-largest-repositories-faster/

Today, the ability to prebuild codespaces is entering public beta. Prebuilding a codespace enables fast environment creation times, regardless of the size or complexity of your repositories. A prebuilt codespace will serve as a “ready-to-go” template where your source code, editor extensions, project dependencies, commands, and configurations have already been downloaded, installed, and applied so that you don’t have to wait for these tasks to finish each time you create a new codespace.

Getting to public beta

Our primary goal with Codespaces is to provide a one-click onboarding solution that enables developers to get started on a project quickly without performing any manual setup. However, because a codespace needs to clone your repository and (optionally) build a custom Dockerfile, install project dependencies and editor extensions, initialize scripts, and so on in order to bootstrap the development environment, there can be significant variability in the startup times that developers actually experience. A lot of this depends on the repository size and the complexity of a configuration.

As some of you might be aware, migrating to Codespaces transformed how we develop at GitHub.

Prebuilds were a huge part of how we meaningfully reduced the time-to-bootstrap in Codespaces for our core GitHub.com codebase. With that, our next mission was to replicate this success and enable the experience for our customers. Over the past few months, we ran a private preview for prebuilds with approximately 50 organizations. Overall, we received positive feedback on the ability of prebuilds to improve productivity for teams working on complex projects. At the same time, we also received a ton of valuable feedback around the configuration and management of prebuilds, and we’re excited to share those improvements with you today:

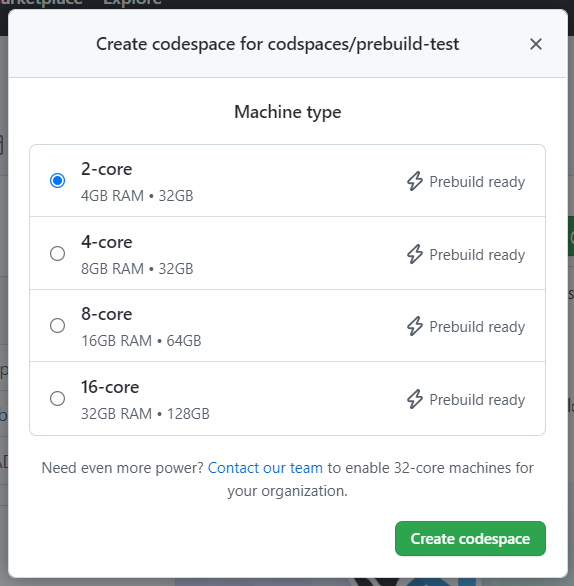
  • You can now identify and quickly get started with a fast create experience by selecting machine types that have a “prebuild ready” tag.
  • A seamless configuration experience helps repository admins easily set up and manage prebuild configurations for different branches and regions.
  • To reduce the burden on repository admins around managing Action version updates for each prebuilt branch, we introduced support for GitHub Actions workflows that will be managed by the Codespaces service.
  • Prebuild configurations are now built on GitHub Actions virtual machines. This enables faster prebuild template creations for each push made to your repository, and also provides repository admins with access to a rich set of logs to help with efficient debugging in case failures occur.

Our goal is to keep iterating on this experience based on the feedback captured during public beta and to continue our mission of enabling a seamless developer onboarding experience.

So how do prebuilds work?

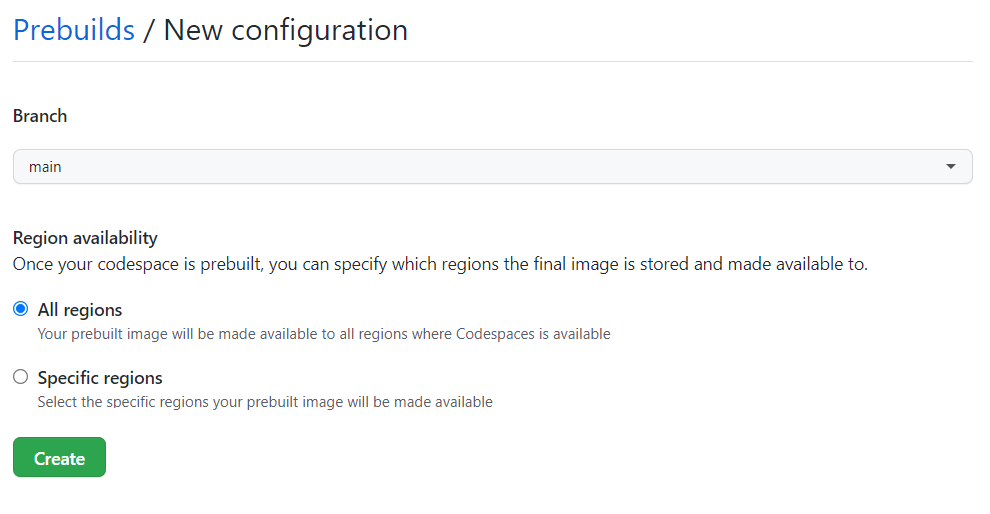
During public beta, repository admins will be able to create prebuild configurations for specific branches and region(s) in their repository.

Screenshot of UI showing prebuild configuration options for a branch

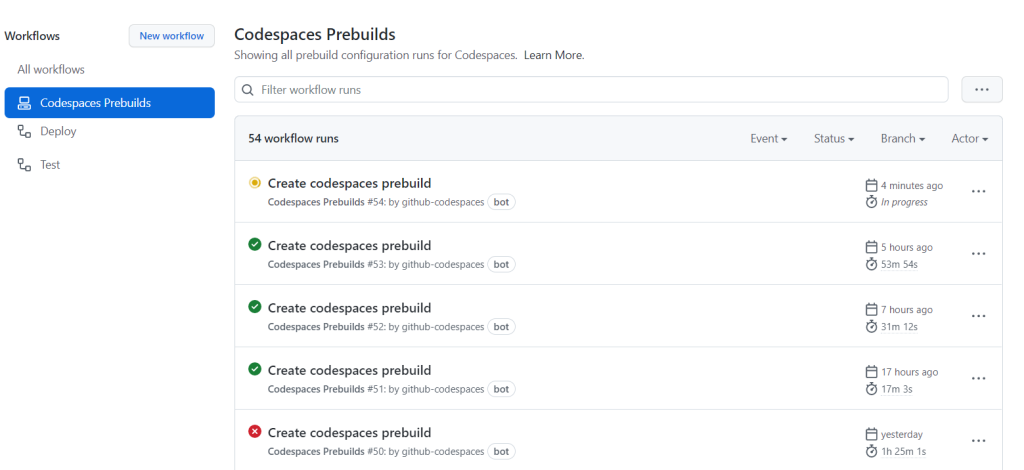
Prebuild configurations will automatically trigger an associated GitHub Actions workflow, managed by the Codespaces service, that will take care of prebuilding the devcontainer configuration and any subsequent commits for that branch. Associated prebuild templates will be stored in blob storage for each of the selected regions.

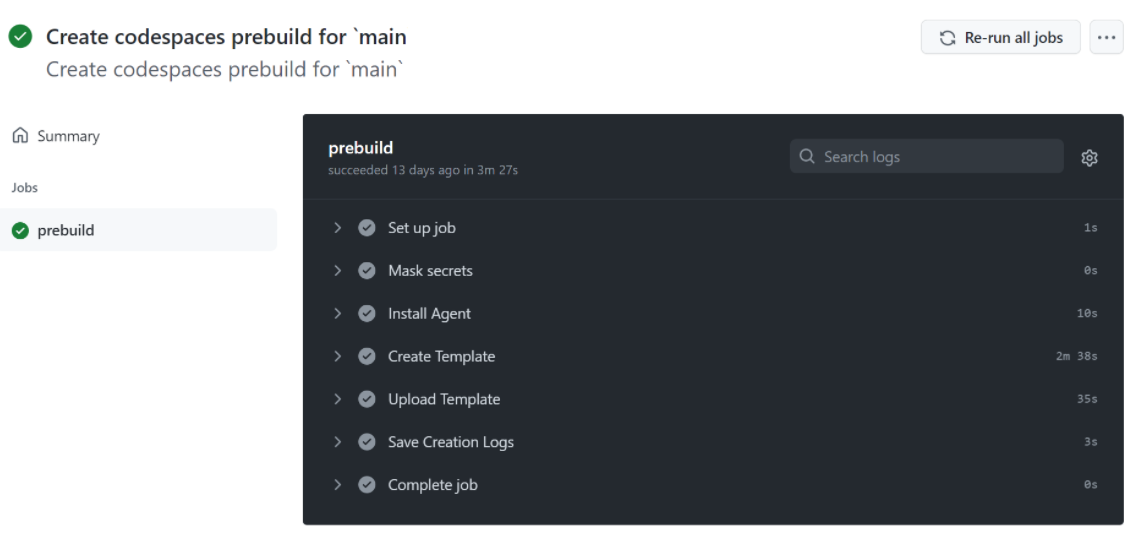
Screenshot of Actions workflow for Codespaces prebuild

Each workflow will provide a rich set of logs to help with debugging in case failures occur.

Screenshot of workflow logs

Every time you request a prebuilt codespace, the service will fetch a prebuilt template and attach it to an existing virtual machine, thus significantly reducing your codespace creation time. To request changes to the prebuild configuration for your branch as per your needs, you can always update its associated devcontainer configuration with a pull request, specifically using the onCreateCommand or updateContentCommand lifecycle scripts.

Screenshot of "prebuild ready" machine options

How to get started

Prebuilds are available to try in public beta for all organizations that are a part of GitHub Enterprise Cloud and Team plans. As an organization or repository admin, you can head over to your repository’s settings page and create prebuild configurations under the “Codespaces” tab. As a developer, you can create a prebuilt codespace by heading over to a prebuild-enabled branch in your repository and selecting a machine type that has the “prebuild ready” label on it.

Here’s a link to the prebuilds documentation to help you get started!

If you have any feedback to help improve this experience, be sure to post it on our discussions forum.

Let’s Architect! Architecting for Security

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-architecting-for-security/

At AWS, security is “job zero” for every employee—it’s even more important than any number one priority. In this Let’s Architect! post, we’ve collected security content to help you protect data, manage access, protect networks and applications, detect and monitor threats, and ensure privacy and compliance.

Managing temporary elevated access to your AWS environment

One challenge many organizations face is maintaining a solid security governance across AWS accounts.

This Security Blog post provides a practical approach to temporarily elevate access for specific users. For example, imagine a developer wants to access a resource in the production environment. With elevated access, you won’t have to provide them an account that has access to the production environment. You would just elevate their access for a short period of time. The following diagram shows the few steps needed to temporarily elevate access to a user.

This diagram shows the few steps needed to temporarily elevate access to a user

This diagram shows the few steps needed for to temporarily elevate access to a user

Security should start left: The problem with shift left

You already know security is job zero at AWS. But it’s not just a technology challenge. The gaps between security, operations, and development cycles are widening. To close these gaps, teams must have real-time visibility and control over their tools, processes, and practices to prevent security breaches.

This re:Invent session shows how establishing relationships, empathy, and understanding between development and operations teams early in the development process helps you maintain the visibility and control you need to keep your applications secure.

Screenshot from re:Invent session

Empowering developers means shifting security left and presenting security issues as early as possible in your process

AWS Security Reference Architecture: Visualize your security

Securing a workload in the cloud can be tough; almost every workload is unique and has different requirements. This re:Invent video shows you how AWS can simplify the security of your workloads, no matter their complexity.

You’ll learn how various services work together and how you can deploy them to meet your security needs. You’ll also see how the AWS Security Reference Architecture can automate common security tasks and expand your security practices for the future. The following diagram shows how AWS Security Reference Architecture provides guidelines for securing your workloads in multiple AWS Regions and accounts.

The AWS Security Reference Architecture provides guidelines for securing your workloads in multiple AWS Regions and accounts

The AWS Security Reference Architecture provides guidelines for securing your workloads in multiple AWS Regions and accounts

Network security for serverless workloads

Serverless technologies can improve your security posture. You can build layers of control and security with AWS managed and abstracted services, meaning that you don’t have to do as much security work and can focus on building your system.

This video from re:Invent provides serverless strategies to consider to gain greater control of networking security. You will learn patterns to implement security at the edge, as well as options for controlling an AWS Lambda function’s network traffic. These strategies are designed to securely access resources (for example, databases) placed in a virtual private cloud (VPC), as well as resources outside of a VPC. The following screenshot shows how
Lambda functions can run in a VPC and connect to services like Amazon DynamoDB using VPC gateway endpoints.

Lambda functions can run in a VPC and connect to services like Amazon DynamoDB using VPC gateway endpoints

Lambda functions can run in a VPC and connect to services like Amazon DynamoDB using VPC gateway endpoints

See you next time!

Thanks for reading! If you’re looking for more ways to architect your workload for security, check out Best Practices for Security, Identity, & Compliance in the AWS Architecture Center.

See you in a couple of weeks when we discuss the best tools offered by AWS for software architects!

Other posts in this series

Biesheuvel: Mitigating kernel risks on 32-bit ARM

Post Syndicated from original https://lwn.net/Articles/885912/

Ard Biesheuvel writes
about 32-bit Arm systems
on the Google Security Blog, with a focus on
why these processors are still in use and what is being done to increase
their security at the kernel level.

Preventing stack overflows from corrupting unrelated memory
contents is the goal of VMAP_STACK, which we are enabling
for 32-bit ARM
as well. When VMAP_STACK is enabled, kernel mode
stacks are allocated from the kernel heap as before, but mapped
into a different part of the kernel’s address space, and surrounded
by guard regions, which are guaranteed to be kept
unpopulated. Given that accesses to such unpopulated regions will
trigger an exception, the kernel’s memory management layer can step
in and terminate the program as soon as a stack overflow occurs,
and prevent it from causing memory corruption.

The collective thoughts of the interwebz