Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=2tY80kLZm_Y
Vulnerability transparency: strengthening security through responsible disclosure
Post Syndicated from Sri Pulla original https://blog.cloudflare.com/vulnerability-transparency-strengthening-security-through-responsible/
In an era where digital threats evolve faster than ever, cybersecurity isn’t just a back-office concern — it’s a critical business priority. At Cloudflare, we understand the responsibility that comes with operating in a connected world. As part of our ongoing commitment to security and transparency, Cloudflare is proud to have joined the United States Cybersecurity and Infrastructure Security Agency’s (CISA) “Secure by Design” pledge in May 2024.
By signing this pledge, Cloudflare joins a growing coalition of companies committed to strengthening the resilience of the digital ecosystem. This isn’t just symbolic — it’s a concrete step in aligning with cybersecurity best practices and our commitment to protect our customers, partners, and data.
A central goal in CISA’s Secure by Design pledge is promoting transparency in vulnerability reporting. This initiative underscores the importance of proactive security practices and emphasizes transparency in vulnerability management — values that are deeply embedded in Cloudflare’s Product Security program. We believe that openness around vulnerabilities is foundational to earning and maintaining the trust of our customers, partners, and the broader security community.
Transparency in vulnerability reporting is essential for building trust between companies and customers. In 2008, Linus Torvalds noted that disclosure is inherently tied to resolution: “So as far as I’m concerned, disclosing is the fixing of the bug”, emphasizing that resolution must start with visibility. While this mindset might apply well to open-source projects and communities familiar with code and patches, it doesn’t scale easily to non-expert users and enterprise users who require structured, validated, and clearly communicated disclosures regarding a vulnerability’s impact. Today’s threat landscape demands not only rapid remediation of vulnerabilities but also clear disclosure of their nature, impact and resolution. This builds trust with the customer and contributes to the broader collective understanding of common vulnerability classes and emerging systemic flaws.
Common Vulnerabilities and Exposures (CVE) is a catalog of publicly disclosed vulnerabilities and exposures. Each CVE includes a unique identifier, summary, associated metadata like the Common Weakness Enumeration (CWE) and Common Platform Enumeration (CPE), and a severity score that can range from None to Critical.
The format of a CVE ID consists of a fixed prefix, the year of the disclosure and an arbitrary sequence number like CVE-2017-0144. Memorable names such as “EternalBlue” (CVE-2017-0144) are often associated with high-profile exploits to enhance recall.
As an authorized CVE Numbering Authority (CNA), Cloudflare can assign CVE identifiers for vulnerabilities discovered within our products and ecosystems. Cloudflare has been actively involved with MITRE’s CVE program since its founding in 2009. As a CNA, Cloudflare assumes the responsibility to manage disclosure timelines ensuring they are accurate, complete, and valuable to the broader industry.
Cloudflare issues CVEs for vulnerabilities discovered internally and through our Bug Bounty program when they affect open source software and/or our distributed closed source products.
The findings are triaged based on real-world exploitability and impact. Vulnerabilities without a plausible exploitation path, in addition to findings related to test repositories or exposed credentials like API keys, typically do not qualify for CVE issuance.
We recognize that CVE issuance involves nuance, particularly for sophisticated security issues in a complex codebase (for example, the Linux kernel). Issuance relies on impact to users and the likelihood of the exploit, which depends on the complexity of executing an attack. The growing number of CVEs issued industry-wide reflects a broader effort to balance theoretical vulnerabilities against real-world risk.
In scenarios where Cloudflare was impacted by a vulnerability, but the root cause was within another CNA’s scope of products, Cloudflare will not assign the CVE. Instead, Cloudflare may choose other mediums of disclosure, like blog posts.
Our disclosure process begins with internal evaluation of severity and scope, and any potential privacy or compliance impacts. When necessary, we engage our Legal and Security Incident Response Teams (SIRT). For vulnerabilities reported to Cloudflare by external entities via our Bug Bounty program, our standard disclosure timeline is within 90 days. This timeline allows us to ensure proper remediation, thorough testing, and responsible coordination with affected parties. While we are committed to transparent disclosure, we believe addressing and validating fixes before public release is essential to protect users and uphold system security. For open source projects, we also issue security advisories on the relevant GitHub repositories. Additionally, we encourage external researchers to publish/blog about their findings after issues are remediated. Full details and process of Cloudflare’s external researcher/entity disclosure policy can be found via our Bug Bounty program policy page
To date, Cloudflare has issued and disclosed multiple CVEs. Because of the security platforms and products that Cloudflare builds, vulnerabilities have primarily been in the areas of denial of service, local privilege escalation, logical flaws, and improper input validation. Cloudflare also believes in collaboration and open sources of some of our software stack, therefore CVEs in these repositories are also promptly disclosed.
Cloudflare disclosures can be found here. Below are some of the most notable vulnerabilities disclosed by Cloudflare:
Cloudflare quiche (through version 0.19.1/0.20.0) was affected by an unlimited resource allocation vulnerability causing rapid increase of memory usage of the system running a quiche server or client.
A remote attacker could take advantage of this vulnerability by repeatedly sending an unlimited number of 1-RTT CRYPTO frames after previously completing the QUIC handshake.
Exploitation was possible for the duration of the connection, which could be extended by the attacker.
quiche 0.19.2 and 0.20.1 are the earliest versions containing the fix for this issue.
CVE-2024-0212: Cloudflare WordPress plugin enables information disclosure of Cloudflare API (for low-privilege users)
The Cloudflare WordPress plugin was found to be vulnerable to improper authentication. The vulnerability enables attackers with a lower privileged account to access data from the Cloudflare API.
The issue has been fixed in version >= 4.12.3 of the plugin
The Cloudflare WARP client for Windows assigns loopback IPv4 addresses for the DNS servers, since WARP acts as a local DNS server that performs DNS queries securely. However, if a user is connected to WARP over an IPv6-capable network, the WARP client did not assign loopback IPv6 addresses but rather Unique Local Addresses, which under certain conditions could point towards unknown devices in the same local network, enabling an attacker to view DNS queries made by the device.
This issue was patched in version 2023.7.160.0 of the WARP client (Windows).
An improper privilege management vulnerability in Cloudflare WARP for Windows allowed file manipulation by low-privilege users. Specifically, a user with limited system permissions could create symbolic links within the C:\ProgramData\Cloudflare\warp-diag-partials directory. When the “Reset all settings” feature is triggered, the WARP service — running with SYSTEM-level privileges — followed these symlinks and may delete files outside the intended directory, potentially including files owned by the SYSTEM user.
This vulnerability affected versions of WARP prior to 2024.12.492.0.
CVE-2025-23419: TLS client authentication can be bypassed due to ticket resumption (disclosed Cloudflare impact via blog post)
Cloudflare’s mutual TLS implementation caused a vulnerability in the session resumption handling. The underlying issue originated from BoringSSL’s process to resume TLS sessions. BoringSSL stored client certificates, which were reused from the original session (without revalidating the full certificate chain) and the original handshake’s verification status was not re-validated.
While Cloudflare was impacted by the vulnerability, the root cause was within NGINX’s implementation, making F5 the appropriate CNA to assign the CVE. This is an example of alternate mediums of disclosure that Cloudflare sometimes opt for. This issue was fixed as per guidance from the respective CVE — please see our blog post for more details.
Irrespective of the industry, if your organization builds software, we encourage you to familiarize yourself with CISA’s “Secure by Design” principles and create a plan to implement them in your company. The CISA Secure by Design pledge is built around seven security goals, prioritizing the security of customers, and challenges organizations to think differently about security.
As we continue to enhance our security posture, Cloudflare remains committed to enhancing our internal practices, investing in tooling and automation, and sharing knowledge with the community. CVE transparency is not a one-time initiative — it’s a sustained effort rooted in openness, discipline, and technical excellence. By embedding these values in how we design, build and secure our products, we aim to meet and exceed expectations set out in the CISA pledge and make the Internet more secure, faster and reliable!
For more updates on our CISA progress, review our related blog posts. Cloudflare has delivered five of the seven CISA Secure by Design pledge goals, and we aim to complete the remainder of the pledge goals in May 2025.
How LaunchDarkly migrated to Amazon MWAA to achieve efficiency and scale
Post Syndicated from Asena Uyar, Dean Verhey original https://aws.amazon.com/blogs/big-data/how-launchdarkly-migrated-to-amazon-mwaa-to-achieve-efficiency-and-scale/
This is a guest post coauthored with LaunchDarkly.
The LaunchDarkly feature management platform equips software teams to proactively reduce the risk of shipping bad software and AI applications while accelerating their release velocity. In this post, we explore how LaunchDarkly scaled the internal analytics platform up to 14,000 tasks per day, with minimal increase in costs, after migrating from another vendor-managed Apache Airflow solution to AWS, using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) and Amazon Elastic Container Service (Amazon ECS). We walk you through the issues we ran into during the migration, the technical solution we implemented, the trade-offs we made, and lessons we learned along the way.
The challenge
LaunchDarkly has a mission to enable high-velocity teams to release, monitor, and optimize software in production. The centralized data team is responsible for tracking how LaunchDarkly is progressing toward that mission. Additionally, this team is responsible for the majority of the company’s internal data needs, which include ingesting, warehousing, and reporting on the company’s data. Some of the large datasets we manage include product usage, customer engagement, revenue, and marketing data.
As the company grew, our data volume increased, and the complexity and use cases of our workloads expanded exponentially. While using other vendor-managed Airflow-based solutions, our data analytics team faced new challenges on time to integrate and onboard new AWS services, data locality, and a non-centralized orchestration and monitoring solution across different engineering teams within the organization.
Solution overview
LaunchDarkly has a long history of using AWS services to solve business use cases, such as scaling our ingestion from 1 TB to 100 TB per day with Amazon Kinesis Data Streams. Similarly, migrating to Amazon MWAA helped us scale and optimize our internal extract, transform, and load (ETL) pipelines. We used existing monitoring and infrastructure as code (IaC) implementations and eventually extended Amazon MWAA to other teams, establishing it as a centralized batch processing solution orchestrating multiple AWS services.
The solution for our transformation jobs include the following components:
- A central Amazon MWAA environment responsible for orchestration
- An ECS cluster and AWS Fargate task definition for running tasks
- Amazon CloudWatch and Datadog for monitoring
- Amazon Elastic Container Registry (Amazon ECR) as the container registry
- Amazon Simple Storage Service (Amazon S3) for artifact storage
- AWS Secrets Manager as a secret store for Amazon MWAA and Amazon ECS
Our original plan for the Amazon MWAA migration was:
- Create a new Amazon MWAA instance using Terraform following LaunchDarkly service standards.
- Lift and shift (or rehost) our code base from Airflow 1.12 to Airflow 2.5.1 on the original cloud provider to the same version on Amazon MWAA.
- Cut over all Directed Acyclic Graph (DAG) runs to AWS.
- Upgrade to Airflow 2.
- With the flexibility and ease of integration within AWS ecosystem, iteratively make enhancements around containerization, logging, and continuous deployment.
Steps 1 and 2 were executed quickly—we used the Terraform AWS provider and the existing LaunchDarkly Terraform infrastructure to build a reusable Amazon MWAA module initially at Airflow version 1.12. We had an Amazon MWAA instance and the supporting pieces (CloudWatch and artifacts S3 bucket) running on AWS within a week.
When we started cutting over DAGs to Amazon MWAA in Step 3, we ran into some issues. At the time of migration, our Airflow code base was centered around a custom operator implementation that created a Python virtual environment for our workload requirements on the Airflow worker disk assigned to the task. By trial and error in our migration attempt, we learned that this custom operator was essentially dependent on the behavior and isolation of Airflow’s Kubernetes executors used in the original cloud provider platform. When we began to run our DAGs concurrently on Amazon MWAA (which uses Celery Executor workers that behave differently), we ran into a few transient issues where the behavior of that custom operator could affect other running DAGs.
At this time, we took a step back and evaluated solutions for promoting isolation between our running tasks, eventually landing on Fargate for ECS tasks that could be started from Amazon MWAA. We had initially planned to move our tasks to their own isolated system rather than having them run directly in Airflow’s Python runtime environment. Due to the circumstances, we decided to advance this requirement, transforming our rehosting project into a refactoring migration.
We chose Amazon ECS on Fargate for its ease of use, existing Airflow integrations (ECSRunTaskOperator), low cost, and lower management overhead compared to a Kubernetes-based solution such as Amazon Elastic Kubernetes Service (Amazon EKS). Although a solution using Amazon EKS would improve the task provisioning time even further, the Amazon ECS solution met the latency requirements of the data analytics team’s batch pipelines. This was acceptable because these queries run for several minutes on a periodic basis, so a couple more minutes for spinning up each ECS task didn’t significantly impact overall performance.
Our first Amazon ECS implementation involved a single container that downloads our project from an artifacts repository on Amazon S3, and runs the command passed to the ECS task. We trigger those tasks using the ECSRunTaskOperator in a DAG in Amazon MWAA, and created a wrapper around the built-in Amazon ECS operator, so analysts and engineers on the data analytics team could create new DAGs just by specifying the commands they were already familiar with.
The following diagram illustrates the DAG and task deployment flows.

When our initial Amazon ECS implementation was complete, we were able to cut all of our existing DAGs over to Amazon MWAA without the prior concurrency issues, because each task ran in its own isolated Amazon ECS task on Fargate.
Within a few months, we proceeded to Step 4 to upgrade our Amazon MWAA instance to Airflow 2. This was a major version upgrade (from 1.12 to 2.5.1), which we implemented by following the Amazon MWAA Migration Guide and subsequently tearing down our legacy resources.
The cost increase of adding Amazon ECS to our pipelines was minimal. This was because our pipelines run on batch schedules, and therefore aren’t active at all times, and Amazon ECS on Fargate only charges for vCPU and memory resources requested to complete the tasks.
As a part of Step 5 for continuous assessment and improvements, we enhanced our Amazon ECS implementation to push logs and metrics to Datadog and CloudWatch. We could monitor for errors and model performance, and catch data test failures alongside existing LaunchDarkly monitoring.
Scaling the solution beyond internal analytics
During the initial implementation for the data analytics team, we created an Amazon MWAA Terraform module, which enabled us to quickly spin up more Amazon MWAA environments and share our work with other engineering teams. This allowed the use of Airflow and Amazon MWAA to power batch pipelines within the LaunchDarkly product itself in a couple of months shortly after the data analytics team completed the initial migration.
The numerous AWS service integrations supported by Airflow, the built-in Amazon provider package, and Amazon MWAA allowed us to expand our usage across teams to use Amazon MWAA as a generic orchestrator for distributed pipelines across services like Amazon Athena, Amazon Relational Database Service (Amazon RDS), and AWS Glue. Since adopting the service, onboarding a new AWS service to Amazon MWAA has been straightforward, typically involving the identification of the existing Airflow Operator or Hook to use, and then connecting the two services with AWS Identity and Access Management (IAM).
Lessons and results
Through our journey of orchestrating data pipelines at scale with Amazon MWAA and Amazon ECS, we’ve gained valuable insights and lessons that have shaped the success of our implementation. One of the key lessons learned was the importance of isolation. During the initial migration to Amazon MWAA, we encountered issues with our custom Airflow operator that relied on the specific behavior of the Kubernetes executors used in the original cloud provider platform. This highlighted the need for isolated task execution to maintain the reliability and scalability of our pipelines.
As we scaled our implementation, we also recognized the importance of monitoring and observability. We enhanced our monitoring and observability by integrating with tools like Datadog and CloudWatch, so we could better monitor errors and model performance and catch data test failures, improving the overall reliability and transparency of our data pipelines.
With the previous Airflow implementation, we were running approximately 100 Airflow tasks per day across one team and two services (Amazon ECS and Snowflake). As of the time of writing this post, we’ve scaled our implementation to three teams, four services, and execution of over 14,000 Airflow tasks per day. Amazon MWAA has become a critical component of our batch processing pipelines, increasing the speed of onboarding new teams, services, and pipelines to our data platform from weeks to days.
Looking ahead, we plan to continue iterating on this solution to expand our use of Amazon MWAA to additional AWS services such as AWS Lambda and Amazon Simple Queue Service (Amazon SQS), and further automate our data workflows to support even greater scalability as our company grows.
Conclusion
Effective data orchestration is essential for organizations to gather and unify data from diverse sources into a centralized, usable format for analysis. By automating this process across teams and services, businesses can transform fragmented data into valuable insights to drive better decision-making. LaunchDarkly has achieved this by using managed services like Amazon MWAA and adopting best practices such as task isolation and observability, enabling the company to accelerate innovation, mitigate risks, and shorten the time-to-value of its product offerings.
If your organization is planning to modernize its data pipelines orchestration, start assessing your current workflow management setup, exploring the capabilities of Amazon MWAA, and considering how containerization could benefit your workflows. With the right tools and approach, you can transform your data operations, drive innovation, and stay ahead of growing data processing demands.
About the Authors
 Asena Uyar is a Software Engineer at LaunchDarkly, focusing on building impactful experimentation products that empower teams to make better decisions. With a background in mathematics, industrial engineering, and data science, Asena has been working in the tech industry for over a decade. Her experience spans various sectors, including SaaS and logistics, and she has spent a significant portion of her career as a Data Platform Engineer, designing and managing large-scale data systems. Asena is passionate about using technology to simplify and optimize workflows, making a real difference in the way teams operate.
 Dean Verhey is a Data Platform Engineer at LaunchDarkly based in Seattle. He’s worked all across data at LaunchDarkly, ranging from internal batch reporting stacks to streaming pipelines powering product features like experimentation and flag usage charts. Prior to LaunchDarkly, he worked in data engineering for a variety of companies, including procurement SaaS, travel startups, and fire/EMS records management. When he’s not working, you can often find him in the mountains skiing.
 Daniel Lopes is a Solutions Architect for ISVs at AWS. His focus is on enabling ISVs to design and build their products in alignment with their business goals with all advantages AWS services can provide them. His areas of interest are event-driven architectures, serverless computing, and generative AI. Outside work, Daniel mentors his kids in video games and pop culture.
Simplify enterprise data access using the Amazon Redshift integration with Amazon S3 Access Grants
Post Syndicated from Maneesh Sharma original https://aws.amazon.com/blogs/big-data/simplify-enterprise-data-access-using-the-amazon-redshift-integration-with-amazon-s3-access-grants/
Scaling data access securely while maintaining operational efficiency is a critical challenge for organizations. Access rights are often fragmented across various AWS services, as different business units own and manage different data stores, such as Amazon Simple Storage Service (Amazon S3) and Amazon Redshift. As data grows, modeling access in AWS Identity and Access Management (IAM) policies becomes challenging for data owners, as they try to manage access for different groups and users across accounts in the organization. Managing these distributed access rights requires substantial overhead, because security teams and data owners must collaborate to update and monitor permissions to make sure data is only accessible to authorized users.
Recognizing this challenge, the Amazon S3 Access Grants integration with Amazon Redshift allows centralized user authentication through AWS IAM Identity Center, providing unified identity across the organization. S3 Access Grants allows specific IAM Identity Center users or groups to access registered Amazon S3 locations through a grant. Creating a grant with a group as grantee lets the group members access only the S3 bucket, prefix, or object within the grant’s scope. This means that access can be managed by simply creating a grant for a group and adding or removing the user from the group, reducing administrative overhead.
In this post, we show how to grant Amazon S3 permissions to IAM Identity Center users and groups using S3 Access Grants. We also test the integration using an IAM Identity Center federated user to unload data from Amazon Redshift to Amazon S3 and load data from Amazon S3 to Amazon Redshift.
Solution overview
This post covers a use case where a large organization manages thousands of corporate users across multiple business units through their identity provider (IdP). These users regularly interact with vast amounts of data stored across numerous S3 buckets, frequently performing extract, transform, and load (ETL) operations through Amazon Redshift. Their goal is to have a simpler ETL process of data loading and unloading operations in Amazon Redshift without managing multiple IAM roles and policies for Amazon S3 access. Also, they want a centralized access management solution that seamlessly integrates their corporate identities from existing IdP with AWS services.
For this solution, AWS Organizations is enabled and IAM Identity Center is configured in the delegated administration account. The organization has two member accounts: Member Account 1 runs analytical workloads on Amazon Redshift, with all the services enabled with trusted identity propagation, and Member Account 2 manages data stored in Amazon S3; here you will set up S3 Access Grants. Amazon Redshift will load the user-specific data from Amazon S3 stored in Member Account 2 using access control based on IAM Identity Center users and groups. This improves the user experience maintaining a single authentication mechanism within an organization, retaining access control, and resource separation using AWS accounts as a boundary per business units.
The following diagram illustrates the solution architecture.

Figure 1: Architecture showing the solution
To run this solution in a single account, configure Amazon Redshift and S3 Access Grants with account instances of IAM Identity Center. Review When to use account instances for more information.
The solution workflow includes the following steps:
- The user configures and connects with their respective clients (such as Amazon Redshift Query Editor v2 or a SQL client) to access Amazon Redshift using IAM Identity Center.
- A new browser windows opens and is redirected to the login page of the IdP.
- The user logs in with their IdP user name and password.
- After the login is successful, the user is redirected to the client application, such as the Amazon Redshift Query Editor.
- When the user tries to access data in Amazon S3 using the LOAD or UNLOAD SQL command, Amazon Redshift in Member Account 1 will request credentials from the S3 Access Grants instance from Member Account 2, where the Amazon S3 data is stored. This request will contain the user context.
- S3 Access Grants will then evaluate the request against the grants it has, matching the identity specified in the grant with the one received in the request. If there is a match, the requestor will receive temporary access to the Amazon S3 locations specified in the grant’s scope.
To implement the solution, we walk you through the following steps:
- Enable S3 Access Grants in your Amazon Redshift managed application.
- Update IAM role permissions used in the application.
- Create a bucket for S3 Access Grants.
- Create an IAM policy and role for S3 Access Grants.
- Set up S3 Access Grants.
- Allow cross-account access of resources.
- Create Redshift tables.
- Unload and load data in Amazon Redshift.
Prerequisites
You should have the following prerequisites already set up:
- IAM Identity Center is enabled with a delegated administration account. For more information, see Enable IAM Identity Center and Register a member account. Keep the IAM Identity Center instance ID and the IAM Identity Center delegated administrator account number.
- Connect IAM Identity Center with your preferred IdP and sync users and groups. For instructions, refer to IAM Identity Center identity source tutorials.
- Two member accounts:
- One with an existing Redshift cluster and managed application (Member Account 1). To set up a Redshift cluster with IAM Identity Center integration enabled, refer to Integrate Identity Provider (IdP) with Amazon Redshift Query Editor V2 using AWS IAM Identity Center for seamless Single Sign-On.
- The second account for Amazon S3 (Member Account 2). You will set up Amazon S3 and S3 Access Grants later in this post.
- Resource sharing enabled in your organization with AWS Resource Access Manager (AWS RAM). For instructions, refer to Enable resource sharing within AWS Organizations.
Enable S3 Access Grants from the Amazon Redshift managed application
After you have created your Redshift application in IAM Identity Center, you need to perform the following steps to enable S3 Access Grants in the account where Amazon Redshift exists. For this post, we use Member Account 1:
- Log in to the AWS Management Console as admin.
- On the Amazon Redshift console, choose IAM Identity Center connection in the navigation pane.
- Select the managed Redshift application and choose Edit.
- Choose Amazon S3 access grants in Trusted identity propagation.
- Choose Save changes.
The following screenshot shows the updated configuration.

Figure 2: Redshift managed application
Update the IAM role permission attached to the Amazon Redshift managed application
The Amazon Redshift managed application has an IAM role attached (in the preceding screenshot, you can see the role called IAMIDCRedshiftRole under IAM role for IAM Identity Center access. We now need to modify the policy on this role and add permissions to allow interaction with Amazon S3. Edit the role and add s3:GetAccessGrantsInstanceForPrefix and s3:GetDataAccess as shown in the following policy:
Replace <IAM Identity Center Instance ID> with your IAM Identity Center instance ID and <Delegated Adminstration AWS Account ID> with the account ID where IAM Identity Center is set up. You also need to replace the resource in CrossAccountAccessGrantscasePolicy with your S3 Access Grants instance information.
Create an S3 bucket for S3 Access Grants
In this step, you create a S3 bucket that you want to grant access to or use an existing bucket. For this post, we create a bucket called amzn-s3-demo-bucket. You can choose another appropriate name. For more information, see Creating a general purpose bucket.
The bucket must be located in the same AWS Region as your S3 Access Grants instance and IAM Identity Center.
Next, create two folders in the newly created S3 bucket. If you’re using an existing S3 bucket, identify two folders to use for this walkthrough. For this blog post, we create two folders: awssso-sales and awssso-finance, under a bucket named amzn-s3-demo-bucket. The purpose of creating two folders is so that users from different groups have access only to their respective folder.
Create an IAM policy and role for S3 Access Grants
Complete the following steps to create an IAM policy to scope the permissions for a specific access grant:
- Create an IAM policy with the following permissions. For more information on creating IAM policy, see Create IAM policies. To get additional information on the following specific policy, refer to Register a location.
- Create an IAM role that has permission to access your S3 data in the Region. For more information, see IAM role creation. In this example, we create an IAM role called
iamidcs3accessgrant. You need to attach the preceding policy to the IAM role. - Use the following trust policy for the IAM role:
Set up S3 Access Grants
The S3 Access Grants instance serves as the container for your S3 Access Grants resources, which include registered locations and grants. You can create only one S3 Access Grants instance per Region per account. You can associate this S3 Access Grants instance to your corporate directory with your IAM Identity Center instance. After you’ve done so, you can create grants for your corporate users and groups. S3 Access Grants requires registering a location to map an S3 bucket or prefix to an IAM role, enabling secure access by providing temporary credentials to grantees for that specific location.
Complete the following steps to set up S3 Access Grants:
- On the Amazon S3 console, choose your preferred Region.
- In the navigation pane, choose Access Grants.
- Choose Create S3 Access Grants instance.
- Select Add IAM Identity Center instance in <region> and enter the IAM Identity Center instance Amazon Resource Name (ARN). For this post, we use the delegated administration account IAM Identity Center ARN.
- Choose Next.

Figure 3: S3 Access Grants instance
- After you create an Amazon S3 Access Grants instance in a Region in your account, you register an Amazon S3 location in that instance. For Location scope, choose Browse S3 or enter the S3 URI path to the location that you want to register. After you enter a URI, you can choose View to browse the location. In this example, we provide the scope as s3://amzn-s3-demo-bucket.
- For IAM role, select Choose from existing IAM roles and choose the IAM role you previously created (
iamidcs3accessgrant). - Choose Next.

This will register a location in your S3 Access Grants instance.

Figure 4: S3 Access Grants instance location scope
- You will now create a grant.
- If you selected the default Amazon S3 location, use the Subprefix box to narrow the scope of the access grant. For more information, see Working with grants in S3 Access Grants.
- If you’re granting access only to an object, select Grant scope is an object. In our example, we register the location as
s3://amzn-s3-demo-bucketand then for the subprefix, we specify the folder name followed by an asterisk (awssso-sales/*).
- Under Permissions and access, select the Permission level, either Read, Write, or both. In this example, we select both because we will first unload from Amazon S3 to Amazon Redshift and then copy from the same bucket to Amazon Redshift.
- For Grantee type, choose Directory identity from IAM Identity Center.
- For Directory identity type, you can choose either User or Group. In this example, we choose Group.
- For IAM Identity Center group ID, enter the group ID from IAM Identity Center where user and group information belongs.
To get this value, open the IAM Identity Center console and choose Groups in the navigation pane, then choose one of the groups you want to provide access and copy the value under Group ID. In the following example, we collect the group ID information from the delegated administration account.

Figure 5: IAM Identity Center group information
- Choose Next.

Figure 6: S3 Access Grants instance permissions and access
- Choose Finish.

Figure 7: S3 Access Grants instance review information page


You can view the details of the access grant on the Amazon S3 console, as shown in the following screenshot. For more information, see View a grant.

Figure 8: S3 Access Grants grants
Similarly, you can get the details of a location that’s registered in your S3 Access Grants instance. For more information, see View the details of a registered location.

Figure 9: S3 Access Grants locations
Allow cross-account access of resources and create initial tables
Now we want to share resources to make our cross-account scenario work. This step is only needed if your Amazon Redshift and Amazon S3 resources are in different accounts. This should be done in the account where Amazon S3 is set up. Complete the following steps:
- On the AWS RAM console, in the navigation pane, choose Resource shares.
- Choose Create resource share.
- For Name, enter a descriptive name for the resource share (for example,
s3accessgrant). - For Resources – optional, choose S3 Access Grants. The S3 Access Grants instance you created will be shown; select the default S3 Access Grant instance ARN.
- Choose Next.
- Under Managed permission for s3:AccessGrants, you can choose to associate a managed permission created by AWS with the resource type, choose an existing customer managed permission, or create your own customer managed permission for supported resource types. In this post, we choose the existing permission named
AWSRAMPermissionAccessGrantsData. - Choose Next.
- For Grant access to principals, choose Allow sharing only within your organization and enter the account ID where the Redshift instance exists.
- Choose Add.
- Choose Next.
- Choose Create resource share.
The following screenshot shows the new resource share details.

Figure 10: AWS RAM – create resource share wizard
Create tables in Amazon Redshift
As an Amazon Redshift admin user, you need to first create the tables you will use to unload data. In the following code, we create a new store_sales_s3access table:
Also make sure the following permissions are applied on the respective IAM Identity Center group; this group is represented in Amazon Redshift as a Redshift role. For this post, we grant permissions to the awssso-sales group:
As an Amazon Redshift admin user, you have created a Redshift table and assigned relevant permissions to the Redshift database role awsidc:awssso-sales. Now when an authenticated user that belongs to the group awssso-sales runs a query in Amazon Redshift to access Amazon S3 (such as a COPY, UNLOAD, or Amazon Redshift Spectrum operation), Amazon Redshift retrieves temporary Amazon S3 access credentials scoped to that IAM Identity Center user from S3 Access Grants. Amazon Redshift then uses the retrieved temporary credentials to access the authorized Amazon S3 locations for that query.
Unload and load data in Amazon Redshift
In this step, we log in to the Amazon Redshift Query Editor using IAM Identity Center authentication and run an UNLOAD command to unload data from the table created earlier into the S3 bucket. After that, we run the COPY command to copy information from Amazon S3 into the same table in the same directory we unloaded the data from.
Complete the following steps to access the Amazon Redshift Query Editor with an IAM Identity Center user:
- On the Amazon Redshift console, open the Amazon Redshift Query Editor.
- Choose (right-click) your Redshift instance and choose Create connection.
- Choose IAM Identity Center as your authentication method.
- A pop-up will appear. Because your IdP credentials are already cached, it uses the same credentials and connects to the Amazon Redshift Query Editor using IAM Identity Center authentication.
Now you’re ready to run the SQL queries in Amazon Redshift.
Unload data
As a federated user, you will first run an unload command from the table store_sales in the bucket s3://amzn-s3-demo-bucket/awssso-sales/.
In this post, we run an UNLOAD command as a federated IAM Identity Center user (Ethan), where we will be unloading the data from a Redshift table. Replace the S3 bucket name with the one you created.
The preceding command doesn’t include an IAM role ARN. This simplified syntax not only makes your code more readable, but also reduces the potential for configuration errors. The underlying permissions are handled automatically through S3 Access Grants and trusted identity propagation, maintaining robust security while simplifying permissions management.
Load data
Now we demonstrate a common data workflow using the same federated IAM Identity Center user (Ethan), where we will be running the COPY command accessing the same Amazon S3 location where we previously unloaded our data. Use to following command to load data into a separate table called store_sales_s3access:
If user Ethan tries to unload "sales_schema"."store_sales" in sales_schema to a different folder in the S3 bucket (awssso-finance), they get a permission denied error. This is because access is controlled by S3 Access Grants, and this user doesn’t have a grant to the awssso-finance folder. Use the following command to test the access denied use case:

Figure 11: QEv2 query result error
IAM Identity Center related operations are automatically captured and logged in AWS CloudTrail, offering enhanced visibility and comprehensive audit capabilities. To view detailed error information on the CloudTrail console, choose Event history in the navigation pane, then specify s3.amazonaws.com as the event source and open GetDataAccess.
The following screenshot shows the snippet from the CloudTrail logs showing that user access is denied.

Figure 12: Amazon CloudTrail
Clean up
Complete the following steps to clean up your resources:
- Delete the IdP applications that you created to integrate with IAM Identity Center.
- Delete the IAM Identity Center configuration.
- Delete the Redshift application and the Amazon Redshift provisioned cluster or serverless instance that you created for testing.
- Delete the IAM role and IAM policies that you created in this post.
- Delete the permission set from IAM Identity Center that you created for the Amazon Redshift Query Editor in the management account.
- Delete the S3 bucket and associated S3 Access Grants instance.
Conclusion
In this post, we explored how to integrate Amazon Redshift with S3 Access Grants using IAM Identity Center. We established cross-account access to enable centralized user authentication through IAM Identity Center in the delegated administrator account, while keeping Amazon Redshift and Amazon S3 isolated by business unit in separate member accounts. We also showed simplified versions of running COPY and UNLOAD commands as a federated IAM Identity Center user without using an IAM role ARN. This setup creates a robust and secure analytics environment that streamlines data access for business users.
For additional guidance and detailed documentation, refer to the following key resources:
- Connect Redshift with AWS IAM Identity Center for a single sign-on experience
- Integrate Identity Provider (IdP) with Amazon Redshift Query Editor V2 and SQL Client using AWS IAM Identity Center for seamless Single Sign-On
- Set up cross-account AWS Glue Data Catalog access using AWS Lake Formation and AWS IAM Identity Center with Amazon Redshift and Amazon QuickSight
- Integrate Tableau and Microsoft Entra ID with Amazon Redshift using AWS IAM Identity Center
- Integrate ThoughtSpot with Amazon Redshift using AWS IAM Identity Center
About the Authors
 Maneesh Sharma is a Senior Database Engineer at AWS with more than a decade of experience designing and implementing large-scale data warehouse and analytics solutions. He collaborates with various Amazon Redshift Partners and customers to drive better integration.
 Laura is an Identity Solutions Architect at AWS, where she thrives on helping customers overcome security and identity challenges. In her free time, she enjoys wreck diving and traveling around the world.
 Praveen Kumar Ramakrishnan is a Senior Software Engineer at AWS. He has nearly 20 years of experience spanning various domains including filesystems, storage virtualization and network security. At AWS, he focuses on enhancing the Redshift data security.
 Yanzhu Ji is a Product Manager in the Amazon Redshift team. She has experience in product vision and strategy in industry-leading data products and platforms. She has outstanding skill in building substantial software products using web development, system design, database, and distributed programming techniques. In her personal life, Yanzhu likes painting, photography, and playing tennis.
Navigate Bulk Sender Requirements with Amazon SES
Post Syndicated from Vinay Ujjini original https://aws.amazon.com/blogs/messaging-and-targeting/navigate-bulk-sender-requirements-with-amazon-ses/
Introduction
Email communication remains a critical component of business operations and customer engagement. As the digital landscape evolves, major mailbox providers continually update their policies to enhance security and user experience. This blog will explore the changes implemented by Microsoft for bulk senders trying to reach Outlook.com (supporting Hotmail.com, live.com consumer domain addresses). This follows the Google & Yahoo! bulk sender requirements changes in February of 2024. Microsoft is implementing the enforcement of sender requirements for bulk email senders, particularly those sending over 5,000 messages daily, starting May 5, 2025. These requirements focus on improving email authentication and trust. This will ensure Outlook and Hotmail recipients are receiving messages that are authenticated and from who they claim to be from. These measures will help reduce spoofing, phishing, and spam, and safeguarding individuals and businesses relying on email.
This blog will discuss what these changes mean for you, and how Amazon Simple Email Service (Amazon SES) can help you maintain compliance and optimize your email sending practices.
Background
In February 2024, Google and Yahoo implemented new requirements for bulk email senders, building upon industry efforts to combat spam and improve email deliverability. These changes aligned with Google’s 2024 bulk sender requirements initiative, signaling a unified approach among major mailbox providers to enhance the privacy and compliance in email.
What does this mean for customers and email senders?
What’s Changing?
Microsoft’s New Requirements
- DMARC enforcement with at least a p=none policy
- Sender domain authentication (SPF, DKIM)
- Functional unsubscribe links required in the email
- Requirement for From and Reply-to addresses to be deliverable
Why These Changes Matter?
These new requirements serve several crucial purposes:
- Enhances trust in your sending domain: Validates that the sender is who they are claiming to be. Enhances trust by delivering messages that are authenticated and aligned with the bulk sender requirements.
- Improved Deliverability: Ensuring legitimate emails reach the recipients who have subscribed to sender’s messages.
- User-Centric: Providing recipients with control over their inboxes.
- Industry Standardization: Aligning sender requirements across major email providers
Best Practices for Compliance
To adhere to these new requirements and optimize your email sending practices, consider the following best practices:
1. Implement Strong Authentication
- Configure SPF: SPF (Sender Policy Framework) is an email authentication standard that’s designed to prevent email spoofing. Domain owners use SPF to tell email providers which servers are allowed to send email from their domains. Follow setup instructions to authenticate your email with SPF. Must pass SPF for sending domain.
- Configure “custom MAIL FROM“, which is how senders can ensure that the SPF-authenticated domain is aligned with the From header domain’s DMARC policy.
- Enable DKIM signing: DomainKeys Identified Mail (DKIM) is an email security standard. It is designed to ensure that an email that claims to have come from a specific domain, was indeed authorized by the owner of that domain. It uses public-key cryptography to sign an email with a private key. Recipient servers use a public key, published to a domain’s DNS to verify that parts of the email have not been modified during the transit. Follow these set up instructions to authenticate email with DKIM in SES. Must pass to validate email integrity and authenticity.
- Verify your domain with Easy DKIM. If currently using email identities, you have to move to domain
- If you utilize email identities only, you will default all authentication to amazonses.com. That will not align with your friendly from address which will not satisfy the bulk sender requirements. This means that when you send email to mailbox providers, your messages will be rejected because you do not have proper authentication on your emails. To satisfy the bulk sender requirements, you must use domain verified identities which ensure that you have ownership of or permission to use the sending domain. That will allow SES to sign the outgoing emails with a DKIM signature that aligns with the friendly from domain.
- Set up DMARC with an appropriate policy: Domain-based Message Authentication, Reporting and Conformance (DMARC) is an email authentication protocol that uses SPF and DKIM to detect email spoofing and phishing. To comply with DMARC, messages must be authenticated through either SPF or DKIM. Ideally, when both are used with DMARC, you’ll be ensuring the highest level of protection possible for your email sending.
| Name | Type | Value |
| _dmarc.example.com | TXT | “v=DMARC1;p=none;rua=mailto:[email protected]“ |
In the preceding records:
-
- example.com is your domain
- Value of the TXT record contains the DMARC policy that applies to your domain.
- In this example, the policy tells email providers to do the following:
- At least p=none should be implemented.
2. Optimize Email Content
- Clearly identify yourself as the sender: Use a recognizable “From” name and email address that accurately represents your brand or organization. For example, use “[email protected]” instead of a generic or misleading address.
- Implement user friendly unsubscribe mechanisms: Include a visible, easy-to-use unsubscribe link in every email, typically in the header. Ensure the unsubscribe process is simple and honors requests promptly, ideally within 24-48 hours. Visit this guide on how Amazon SES helps you do that.
- Subject line aligns with content: Avoid deceptive subject lines that don’t match the email content.
- Clearly identify commercial content: If your email is promotional, make it obvious. Use clear language in the subject line and body that indicates the nature of the email, such as “Special Offer” or “Newsletter.”
- Include a valid physical address: Add your company’s physical mailing address in the email footer. This is not only a legal requirement in many jurisdictions but builds trust with recipients.
- Verify URLS in the emails: Verify that links in the emails you send work and are not misleading to the reader/subscriber. Be transparent with URLs/links in the email content.
3. Monitor and Maintain
- Monitor bounces: A bounce typically indicates why a message was not delivered. The SMTP response in the bounce message will have details on why the message was bounced. For example: if it is missing authentication records (fix: include authentication records for the domain – quick fix) versus an IP or domain reputation bounce reason (this maybe a longer term fix).
- Track both hard bounces (permanent delivery failures) and soft bounces (temporary issues). High bounce rates can indicate list quality problems or delivery issues. Visit this blog to set up notifications for bounces & complaints. Virtual Deliverability Manager (VDM) is an Amazon SES feature that helps you enhance email deliverability. It helps increasing inbox deliverability and email conversions, by providing insights into your sending and delivery data. VDM advices on how to fix the issues that are negatively affecting your delivery success rate and reputation.
- Track complaint rates: Regularly monitor the number of spam complaints your emails receive with a goal of keeping the complaint rate under 0.2%. Not all mailbox providers have complaint feedback loop data, so use aggregate data from the mailbox providers that do, such as Hotmail and Yahoo. Email providers that don’t provide complaint feedback loops, such as Gmail may have alternative dashboards or tools available like Google Postmaster tools.
- Perform regular authentication checks: Periodically verify that your SPF, DKIM, and DMARC records are correctly set up and functioning. Alternative to manual DNS checks, Amazon SES has a feature in Virtual Deliverability Manager that performs authentication checks for your sending identities.
- Maintain list hygiene: Regularly clean your email list by removing inactive subscribers, correcting typos in email addresses, and honoring unsubscribe requests. This helps improve deliverability and engagement rates.
How Amazon SES Helps
Amazon SES provides a robust set of features to help you meet these new requirements and optimize your email sending practices:
Authentication Support
- Easy DKIM configuration
- SPF record management
- DMARC implementation guidance
Comprehensive Monitoring
- Virtual Deliverability Manager
- Complaint tracking
- Bounce rate monitoring
- Event publishing to Amazon CloudWatch, SNS , Kinesis Firehose and Event Bridge
- Detailed sending statistics
Compliance Tools
- List management capabilities (included with SES)
- Suppression list handling (included with SES)
- Feedback loop processing (included with SES)
- Authentication status tracking: This is done through Amazon SES feature Virtual Deliverability Manager (VDM).
Implementation Strategy
To successfully implement these changes, consider the following strategy:
- Assessment: Audit your current email practices, review authentication status, and evaluate compliance gaps.
- Technical Implementation: Configure authentication protocols, update DNS records, and implement required unsubscribe mechanisms.
- Monitoring and Optimization: Track deliverability metrics, monitor complaint rates, and adjust sending practices as needed.
Measuring Success
To ensure ongoing compliance and optimize your email practices, track these key metrics:
- Delivery rates
- Complaint rates
- Authentication pass rates
- Engagement metrics (open rates, click-through rates)
Conclusion
The new bulk sender requirements from Microsoft and Yahoo represent an important step towards a more secure and reliable email ecosystem. By leveraging Amazon SES’s powerful features and following industry best practices, you can maintain compliance, improve deliverability, and enhance the overall effectiveness of your email communications.
Amazon SES is committed to helping you navigate these changes and optimize your email sending practices. For the most up-to-date guidance and support, please consult SES’s documentation or contact Amazon SES support.
Additional Resources
The email landscape is constantly evolving. Stay informed and adaptable to ensure your email practices remain effective and compliant.
About the authors:
VMAX VX4 Scooter: Ultimate Commuter! 100+ MILES Review
Post Syndicated from digiblur DIY original https://www.youtube.com/watch?v=McE8Bi6wvwI
Communications Backdoor in Chinese Power Inverters
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/05/communications-backdoor-in-chinese-power-inverters.html
This is a weird story:
U.S. energy officials are reassessing the risk posed by Chinese-made devices that play a critical role in renewable energy infrastructure after unexplained communication equipment was found inside some of them, two people familiar with the matter said.
[…]
Over the past nine months, undocumented communication devices, including cellular radios, have also been found in some batteries from multiple Chinese suppliers, one of them said.
Reuters was unable to determine how many solar power inverters and batteries they have looked at.
The rogue components provide additional, undocumented communication channels that could allow firewalls to be circumvented remotely, with potentially catastrophic consequences, the two people said.
The article is short on fact and long on innuendo. Both more details and credible named sources would help a lot here.
[$] A kernel developer plays with Home Assistant: case studies
Post Syndicated from corbet original https://lwn.net/Articles/1017945/
The first article in this series provided
an overview of Home Assistant,
its community, and its capabilities. It was deliberately short on
descriptions of interesting things that can be done with Home Assistant,
though — the reasons why one might actually want to use this program. In
this closing article, we’ll look at how Home Assistant was used to solve
some real problems.
An Asahi Linux 6.15 progress report
Post Syndicated from jzb original https://lwn.net/Articles/1021484/
The Asahi Linux
project, which supports Linux on Apple Silicon Macs, has published a
progress report ahead of the 6.15 kernel’s release.
We are pleased to announce that our graphics driver userspace API
(uAPI) has been merged into the Linux kernel. This major milestone
allows us to finally enable OpenGL, OpenCL and Vulkan support for
Apple Silicon in upstream Mesa. This is the only time a graphics
driver’s uAPI has been merged into the kernel independent of the
driver itself, which was kindly allowed by the kernel graphics
subsystem (DRM) maintainers to facilitate upstream Mesa enablement
while the required Rust abstractions make their way upstream. We are
grateful for this one-off exception, made possible with close
collaboration with the kernel community.
Security updates for Friday
Post Syndicated from jzb original https://lwn.net/Articles/1021482/
Security updates have been issued by AlmaLinux (.NET 8.0, .NET 9.0, kernel, kernel-rt, redis:6, and yelp and yelp-xsl), Debian (chromium), Red Hat (compat-openssl11, kernel, and thunderbird), and SUSE (nbdkit, open-vm-tools, and rustup).
Best of: Building Railroads
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=wErLbnhzIl0
Валутата на президента
Post Syndicated from Емилия Милчева original https://www.toest.bg/valutata-na-prezidenta/

По-малко от 17 месеца остават до следващите президентски избори, а Румен Радев все още няма яснота за своето политическо бъдеще, след като излезе от „Дондуков“ 2. Тази несигурност го прави уязвим и податлив на инициативи като референдума за еврото. Внушена от външни и вътрешни съветници, тя не ентусиазира особено народа, към когото уж е насочена. След като отправи вечерно обръщение на 9 май и един блед коментар, президентът изчезна от публичното пространство. И проговори в деня, в който отпътува за чужбина, за което се разбра случайно. Радев заминава със съпругата си в Япония, където ще остане до 21 май за участие в Деня на България на Световното изложение ЕКСПО 2025.
През тези осем дни управляващи и опозиция сключиха пакт за примирие и се обединиха в името на еврозоната, а президентското искане за референдум изобщо не стигна до пленарната зала. Държавният глава не направи обръщение в парламента, а предпочете да коментира от летището, без да допусне журналистически въпроси. Съобщи, че ще сезира Конституционния съд (КС) заради отказа на парламента да разгледа предложението му за всенародно допитване за или против въвеждане на еврото през 2026 г. – както го посъветваха и от „Възраждане“.
В изявлението си Радев повтори опасността от инфлация, каквато имало в други държави, въвели единната европейска валута, приписа си заслугите за избуялите дебати, придържайки се към наратива за „eлитите“ и „народа“, станал негова запазена марка.
Моето предложение вече дава резултати. Най-сетне започнаха дебати за реалната ни готовност да приемем еврото следващата година. Най-сетне чухме от устатата на господата Пеевски и Борисов думите „цени“ и „нужда от контрол“. Твърде късно и под натиск.
Председателката на 51-вото Народно събрание Наталия Киселова му върна искането за референдум като недопустимо, а в писмена позиция от Президентството определиха действието като „отдалечаване от демокрацията и законността“.
Правните основания за решението на Киселова са следните:
Предложението не беше разпределено [за разглеждане – б.а.], тъй като не е в съответствие с чл. 5, ал. 4 във връзка с чл. 4, ал. 3 и чл. 85, ал. 3 от Конституцията на Република България, чл. 140, параграфи 1 и 2 от Договора за функционирането на Европейския съюз, чл. 3 от Договора за присъединяване на Република България към Европейския съюз, чл. 5 от Акта относно условията за присъединяване на Република България и Румъния и промените в Учредителните договори и чл. 9, ал. 4 от Закона за пряко участие на гражданите в държавната власт и местното самоуправление.
Предложението на държавния глава и мотивите към него не са съобразени с мотивите и диспозитива на Решение №3 на Конституционния съд от 2024 г. по к.д. №13/2023 г.
Наистина КС вече се произнесе: референдум за отлагане на приемането на еврото нe може да има. Партия „Възраждане“ предложи всенародно допитване с въпрос „Съгласни ли сте българският лев да бъде единствена официална валута в България до 2043 г.?“, но парламентът го отхвърли.
Причината е, че чл. 9, ал. 4 от Закона за пряко участие на гражданите в държавната власт и местното самоуправление забранява с референдум да се решават въпроси, уредени в сключени от България международни договори. Плебисцит е възможен преди ратификацията им – за еврото е бил допустим преди 11 май 2005 г., когато парламентът ратифицира Договора за присъединяване към ЕС.
Заради решението на КС от „Възраждане“ струпаха животински изпражнения пред институцията, изгориха бали сено и дори подпалиха автомобил. Но освен тези провокации, недопускането на референдума не отприщи по-силни народни вълнения.
Иронично или не, сега именно президентското искане доведе до нещо рядко – обединение на управляващи и опозиция, за да препотвърдят еврозоната като стратегическа цел. Направиха го и синдикати, бизнес, представители на академичната общност. В декларация преподаватели по право от български университети се обявиха срещу референдума. По Нова телевизия доц. Христо Христев от Софийския университет обясни позицията им:
… евентуалното свикване на референдума би означавало суспендиране на установения конституционен модел за вземане на решения в основни институции на България.
Всъщност след изявлението на Радев наистина започна същинската информационна кампания за еврото, при това три седмици преди Европейската комисия и Европейската централна банка (ЕЦБ) да излязат с конвергентните доклади. Индикативната дата за тях е 4 юни, а правителството е препотвърдило искането си, както се разбра от еврокомисаря по икономиката Валдис Домбровскис:
Не мога да коментирам вътрешни работи, но проведохме разговор с министъра на финансите Петкова заедно с ЕЦБ и президента на Еврогрупата. Посланието на министър Петкова беше много ясно – българското правителство заедно с БНБ подадоха искане за конвергентен доклад. И те се придържат към искането си. В отговор Комисията и ЕЦБ продължават да работят върху изготвянето му и се предвижда работата по него да приключи в началото на юни.
Партии vs. Румен Радев
Защо преподавателката по конституционно право Наталия Киселова не допусна искането за референдум в пленарната зала? Преди това авторитетни юристи като проф. Екатерина Михайлова предложиха същото. „Ако предложението за референдум бъде върнато като недопустимо от Народното събрание, президентът няма какво да изпрати на КС“, обясни по Нова телевизия проф. Михайлова.
Лидерът на „Възраждане“ Костадин Костадинов публично предложи правна помощ на екипа на президента, за да поиска тълкувателно решение от КС за отказа на Киселова. Което Радев и направи.
Ако неговият екип има проблеми с написването на подобно искане до Конституционния съд, и ние, и всеки един от не особено добрите юристи в страната може да помогне.
Това иронично-подигравателно отношение от съмишленик към съмишленик е доказателство, че на Радев вече гледат като на „колега“, бъдещ играч на партийния терен. Парадоксално – човекът, който винаги е назидавал партиите за тяхната неефективност, унижавал е парламентарната република, обмисля партиен проект. Само че така и не събира смелост да го направи.
С действията си обаче президентът предизвика ситуационно обединение на политически сили срещу себе си. Изключение правят „Величие“, които бранят позициите му и даже вредния за българските национални интереси договор с „Боташ“, и „Възраждане“, но те ревнуват, понеже са убедени, че имат патент върху битката срещу еврото.
ГЕРБ–СДС, ПП–ДБ, двете ДПС-та и дори БСП обявиха, че ако искането за референдум влезе в пленарната зала, ще гласуват против. „Има такъв народ“ – партията, която първа подкрепи Радев за втори мандат, е за референдум (предвид своя генезис). Но както обясни Тошко Йорданов, в случай че има такъв, ще агитират за еврото.
ГЕРБ–СДС и „Демократична България“ видяха откровен саботаж в искането на президента. Според лидера на ГЕРБ Бойко Борисов президентът е решил в последния момент „да бламира България и да не можем да влезем в еврозоната“:
Никой не казва, че е срещу еврозоната, а започват да определят някакви дати – сиреч да излъжат избирателите си. Просто него го е яд, че правителството и парламентът се справиха и си изпълниха критериите. Единственият начин да бъдем спрени от еврозоната е да покажем нестабилност.
Съпредседателят на „Да, България“ (от обединението ДБ) Ивайло Мирчев определи хода на президента като „част от неговия политически проект“.
Безпрецедентното изявление на президента Румен Радев за референдум за еврото е саботаж срещу влизането ни в еврозоната, няма по-грубо и безотговорно действие срещу националния интерес.
Съпредседателят на „Продължаваме промяната“ Асен Василев нарече инициативата на Радев „провокация“.
Последните няколко месеца върви една изключително агресивна дезинформационна кампания, която да плаши хората, че ще им вземат парите, влоговете… Чухте, даже вицепрезидентът Йотова каза, че това е лъжа. Но на тази лъжа последните проучвания показаха, че 40% от българите са ѝ повярвали.
Лидерът на ДПС – Ново начало Делян Пеевски смята, че целта на президента е да всее раздор и противопоставяне в обществото с предложението си.
Изказването на Радев от 19 часа в Деня на Европа е толкова несъстоятелно, че заради институцията, не заради персоната с неосъществени мераци, трябва снизходително да се престорим, че не се е случило.
„Потъпкват демокрацията…“
За да се подгрява темата, публични говорители, свързвани с Радев, излизат с рефрена, че е потъпкана демокрацията с недопускането на референдума. Самият държавен глава даде тон за този разказ в единствения коментар, преди да замине за Япония. Но същността на искането му е да спъне България по пътя към еврото, опаковано като допитване до народа.
Инициативата на президента ще всее допълнително недоверие в разделеното българското общество, силно облъчвано с дезинформационни кампании и руска пропаганда. Но дали ще изцеди обществено недоволство, което да го направи народен трибун, по-голям от проруските евроскептици Костадинов, Михайлов и Василев, взети заедно? Радев започна втория си мандат с 58,5% доверие и с недоверие от 32,1% и макар последни проучвания да показват лек спад – 47% доверие срещу 31% недоверие, той остава единственият с позитивен нетен рейтинг.
В първия си мандат Румен Радев печелеше симпатии с позиционирането си срещу статуквото и беше възприеман от гражданите като символ на борбата срещу задкулисието и корупцията, а също и за „морален съдник за правителството“, както го определи проф. Милена Стефанова. Забрави се неизпълненото му обещание да предложи законопроект за промени в Конституцията.
Онова, което ще се запомни от неприключилия втори мандат, е противопоставянето му по две ключови теми, знакови за европейската принадлежност и европейска интеграция на България: подкрепа и помощ за Украйна и единната европейска валута. Наклонът към руския агресор, демонстриран от Радев и от служебните му правителства, поставиха България редом до Орбанова Унгария в ЕС и нанесоха репутационни щети. Към тези „заслуги“ се прибави и вредният 13-годишен договор с турската компания „Боташ“, сключен от служебен кабинет на президента. Тази договорка влошава финансовото състояние на „Булгаргаз“ – за 2024 г. компанията е на загуба с 280 млн. лв., а към 31 март 2025 г. дължи на „Боташ“ 250 млн. лв.
По контракта „Булгаргаз“ плаща около един милион лева дневно на „Боташ“ за капацитет, който не ползва, защото цената на газа ще е твърде висока. Почвата за сключването му подготвиха разговори на Радев с турския президент Реджеп Тайип Ердоган през есента на 2022 г. Скоро след това се подписа и споразумението за запазен капацитет за внос на 1,85 млрд. куб.м годишно на турските терминали, а най-скандалното е, че не може да бъде развален, освен ако не се плати цялата сума от над 4 млрд. лв.
Сметката може да достигне и 6 милиарда, обясни в парламента енергийният министър Жечо Станков, извикан на изслушване от депутатите. Чуха се отново факти, известни още от заседания на временната парламентарна комисия от миналата година, свикана, за да ги изясни – например че договорът не е бил представен на министерствата, през които е минал за съгласуване, но има одобрението на Министерския съвет.
Именно във втория мандат пролича най-силно властолюбието на Радев чрез извършените от служебните му кабинети поголовни смени на ръководствата на служби, в държавните дружества и по институциите под контрола на изпълнителната власт. По Българското национално радио проф. Стефанова заяви, че президентът не може да бъде алтернатива на управлението, както не може да бъде и опозиция.
Нормалните президенти някак си излъчват кабинет и не се бъркат в работата му, докато Радев много обичаше да се възпалява като глава на правителството, само дето не можеше да се окичи и с това да е премиер.
Тревогите – зад гърба, страховете – у хората
Фискалният съвет се зае да разбива слуховете за висока инфлация, настъпила в държави, приели еврото. „Този въпрос, който хвърли в голяма тревога демократичната общност в страната, вече е зад гърба ни“, заяви премиерът Росен Желязков след решението на Киселова.
Дали?
„Възраждане“ реши да рестартира битките си срещу еврото с призив към граждани да се съберат пред НДК на 16 май, където в зала 1 ще се обсъждат „превантивни мерки срещу насилственото вкарване на България в еврозоната“.
Преди да отлети за албанската столица Тирана за Срещата на върха на Европейската политическа общност, премиерът благодари на онези 171 народни представители, подкрепили декларацията, подписана от него и от управителя на БНБ Димитър Радев, потвърждаваща решителността на България да приеме еврото от 1 януари 2026 г. Желязков благодари и на бившите премиери Иван Костов и Бойко Борисов и даде обещания:
Отиваме към увеличаване на конкурентоспособността на българската икономика. Когато получим положителната оценка на доклада, ще излезем с редица мерки, за да се изпълнят принципите за въвеждане на еврото – защита на потребителите, информираност и ефективност; ще предложим промени, които трябва да внесат успокоение в българското общество; ще въведем контролни механизми, които ще дадат възможност ефективно да се спазва законодателството и да не се допускат спекула и спекулация.
Страховете на хората обаче не са зад гърба на политиците, съвсем реални са – те са валутата на популизма. Румен Радев си отваря сметка именно в тази валута.
Ivanti Endpoint Manager Mobile exploit chain exploited in the wild
Post Syndicated from Ryan Emmons original https://blog.rapid7.com/2025/05/16/etr-ivanti-epmm-exploit-chain-exploited-in-the-wild/

On May 13, 2025, Ivanti disclosed an exploited in the wild exploit chain, comprising of two new vulnerabilities affecting Ivanti Endpoint Manager Mobile (EPMM): CVE-2025-4427 and CVE-2025-4428. Ivanti EPMM is an enterprise-focused software suite for IT teams to manage mobile devices, applications, and content.
CVE-2025-4427 is an authentication bypass vulnerability with a CVSS rating of 5.3 (Medium). CVE-2025-4428 is an authenticated remote code execution (RCE) vulnerability with a CVSS rating of 7.2 (High). By chaining the medium-severity authentication bypass (CVE-2025-4427), an unauthenticated attacker can reach a web API endpoint to inject server-side template patterns and exploit the high-severity vulnerability (CVE-2025-4428), thus achieving unauthenticated remote code execution. Therefore, while neither vulnerability has been rated as critical, when combined together, the impact of the exploit chain is critical, i.e. unauthenticate RCE.
The vulnerabilities were reported to the vendor by CERT-EU, the European Union’s Cybersecurity Service for the Union institutions, bodies, offices and agencies. The vendor has disclosed that this exploit chain has been exploited in the wild to a limited degree. Notably, this product was previously targeted by an unknown threat actor against the Norwegian Security and Service Organization (DSS) in 2023.
On May 15, 2025, a technical analysis and accompanying proof-of-concept exploit was published publicly. With public exploit code now available, the risk of broad exploitation in the wild has greatly increased.
Mitigation guidance
The vendor has provided patches for affected versions of EPMM. Customers are advised to follow the vendor guidance, and remediate this vulnerability by upgrading to a fixed version on an emergency basis, without waiting for a regular patch cycle to occur.
The following list outlines the affected supported EPMM versions, and their respective fixes:
- Version
11.12.0.4and prior is fixed in version11.12.0.5 - Version
12.3.0.1and prior is fixed in version12.3.0.2 - Version
12.4.0.1and prior is fixed in version12.4.0.2 - Version
12.5.0.0and prior is fixed in version12.5.0.1
For the latest mitigation guidance, please refer to the vendor advisory.
Rapid7 customers
InsightVM and Nexpose customers can assess exposure to CVE-2025-4427 and CVE-2025-4428 with unauthenticated checks expected to be available in today’s (May 16) content release.
Ready, set, Scratch: A beginner’s guide to creative coding
Post Syndicated from Mark Calleja original https://www.raspberrypi.org/blog/ready-set-scratch-a-beginners-guide-to-creative-coding/
What is Scratch?
Scratch is a free, beginner-friendly coding platform that allows young people to create animations, games, and interactive stories using simple visual blocks. Scratch removes some of the complexity of coding by replacing syntax-heavy programming languages with intuitive drag-and-drop blocks. This lets creativity take centre stage and makes it the perfect first step for young coders.
Why Scratch is the ideal starting point
Every coding journey begins with a single step. Scratch delivers this first step in a way that is playful, approachable, and empowering. Scratch immediately delivers tangible results that new coders can feel proud of by linking coding to storytelling, design, and play. It also cultivates curiosity, confidence, and resilience — qualities crucial to long-term success in both coding and problem solving.
Most importantly, Scratch emphasises exploration over perfection. It invites young learners to experiment freely, troubleshoot confidently, and express themselves creatively without fear of making mistakes. This exploratory mindset provides the foundation for future technical proficiency and innovation.
Get started with our free projects
Starting with structured projects helps young learners build solid coding skills while maintaining enthusiasm and enjoyment.
Catch the bus (animation)
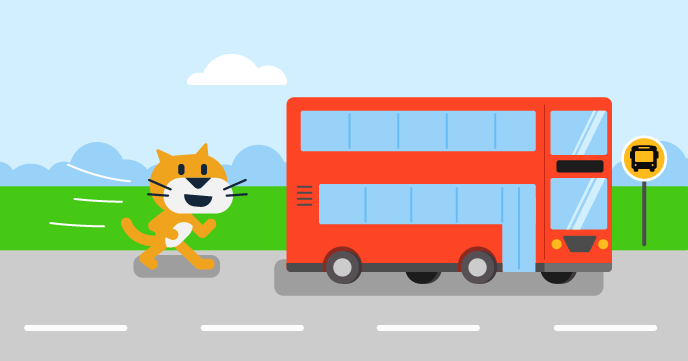
In ‘Catch the bus’, coders create an animation featuring a character (called a sprite in Scratch) attempting to catch a departing bus. They learn how to sequence events, switch costumes to simulate movement, and synchronise actions to tell a simple story. This introduces fundamental storytelling and animation skills in Scratch.
What you’ll learn:
- Timing and sequencing actions
- Using costume changes to simulate movement
- Creating narrative animations
Chomp the cheese (interactive)
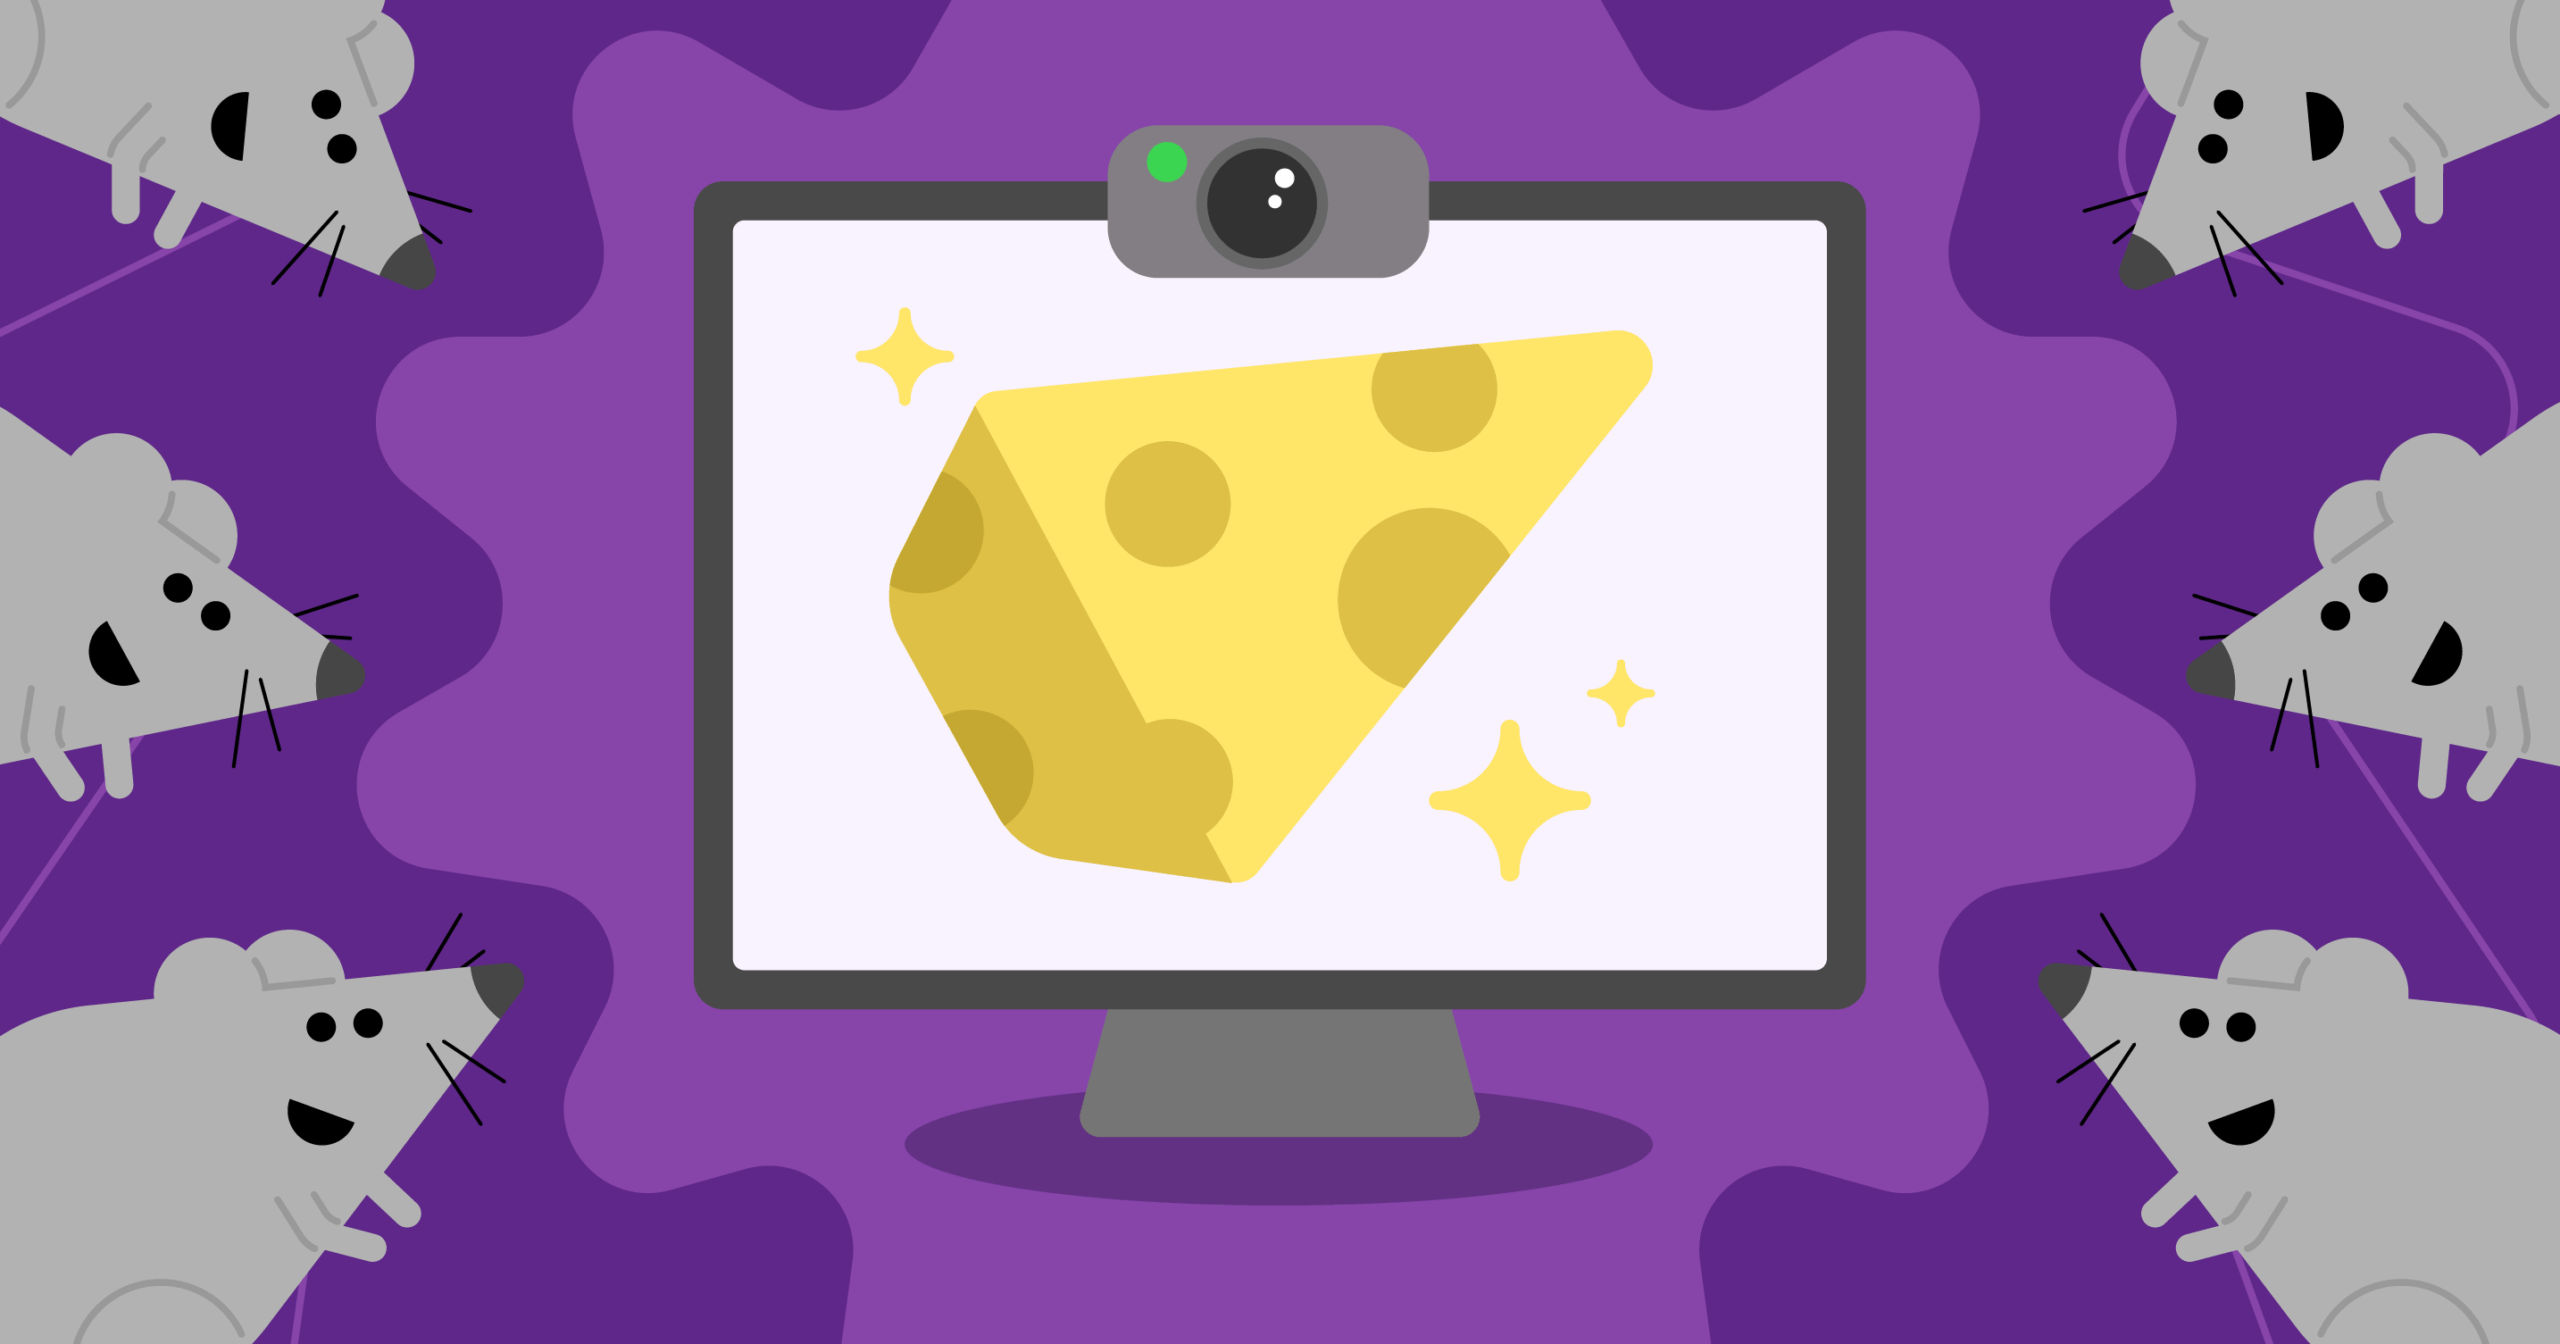
In ‘Chomp the cheese’, learners use facial recognition tools in Scratch Lab to build an interactive game controlled by mouth movements. Using a webcam, players physically open their mouths to “chomp” virtual cheese snacks on screen. This playful and engaging activity introduces machine learning concepts in a tangible and enjoyable way.
What you’ll learn:
- Using facial recognition in Scratch
- Creating interactive games with webcam input
- Basic concepts of machine learning and interactivity
Boat race (game)
In ‘Boat race’, young coders create a game where players navigate a boat around obstacles, steering using mouse controls. They learn to handle player input, detect collisions, and define conditions for winning. This foundational game-making experience sets the stage for more complex creations in the future.
What you’ll learn:
- Controlling sprites with mouse clicks
- Collision detection between sprites
- Defining goals and win conditions
“The key to sparking a lifelong interest in coding is excitement. When young people are building something they genuinely care about, they’re not worried about getting everything perfect on the first try. They’re chasing their ideas and learning as they go. Scratch creates the ideal environment for this type of messy, brilliant exploration. It provides young coders with the freedom to experiment, persevere, and express themselves — all while enjoying the process,” or so says my amazing colleague Pete Bell, Learning Manager and creator of some of our most engaging content at the Raspberry Pi Foundation. I have to say, I agree with him!
Level up and build momentum
After completing their first projects, young coders can continue to build momentum through several exciting avenues:
- Personalise projects: Encourage learners to remix existing projects by altering characters, backgrounds, and rules. Personalisation deepens learning and fosters ownership of the coding experience.
- Explore Python: Scratch’s block-based coding naturally leads to curiosity about text-based languages like Python, which many learners find an exciting next step.
- Join a Code Club: Coding alongside peers transforms individual learning into a social experience. Code Clubs offer a collaborative environment where learners solve problems together, share creations, and build lasting friendships.
Encouraging personalisation, curiosity, and community involvement keeps learners motivated and engaged on their coding journey.
Conclusion
Scratch is more than just an introductory tool — it’s a creative playground that nurtures curiosity, resilience, and technical skills in equal measure. By guiding young coders through their first steps with engaging projects and supportive encouragement, you lay the foundation for a lifetime of innovation, problem-solving, and creative expression. Ready, set, Scratch! Let’s get started!
The post Ready, set, Scratch: A beginner’s guide to creative coding appeared first on Raspberry Pi Foundation.
In Memoriam: John L. Young (EFF)
Post Syndicated from corbet original https://lwn.net/Articles/1021462/
The Electronic Frontier Foundation has posted a somewhat belated memorial
for John Young, the founder of Cryptome.
John was one of the early, under-recognized heroes of the digital
age. He not only saw the promise of digital technology to help
democratize access to information, he brought that idea into being
and nurtured it for many years. We will miss him and his
unswerving commitment to the public’s right to know.
Т.Е. от Е.Т. – епизод 14
Post Syndicated from Тоест original https://www.toest.bg/t-e-ot-e-t-epizod-14/

Замисляме се дали да не я пуснем тази президентска кандидатура към Вселената…
Невидимата сексуалност на хората с увреждания в България
Post Syndicated from Светла Енчева original https://www.toest.bg/nevidimata-seksualnost-na-horata-s-uvrezhdaniya-v-bulgaria/

Правило ли ви е впечатление, че когато се говори за деца с увреждания, нерядко се имат предвид и възрастни? Например в протестите на майки на деца с увреждания участват и родители на хора, които отдавна са навършили пълнолетие. За един родител, разбира се, детето му си е дете, независимо от възрастта. Проблемът обаче е, че доминиращото публично говорене за пълнолетни хора като за деца само защото са с различни възможности, е инфантилизиращо. Защото така се пренебрегват не само потребностите на зрели индивиди отвъд физическото им оцеляване, а и човешкото им достойнство.
„Институционализирана слепота“
Изследователите Венелин Стойчев и Надежда Денева квалифицират законодателната уредба и административните практики по отношение на хората с увреждания с думите „институционализирана слепота“. Те правят тази констатация в доклада на Центъра за независим живот „Правата на „правите“ и правата на „кривите“. Турбуленции по пътя към пълноценната лична, трудова и социална реализация на хората с увреждания в България“. В него се анализират резултатите от проучване, посветено на женствеността на жените с увреждания в България. То включва както количествена анкета, така и интервюта с жени с увреждания, техни близки, социални работници, юристи.
Интервютата хвърлят светлина върху практическите измерения на „институционализираната слепота“. Ето какво споделя социален работник например:
Имахме случай на жена със зрително увреждане, която искаше повече часове лична помощ, защото се грижи за детето си. Тогава си дадохме сметка, че Законът за личната помощ е ориентиран само около физиологичните нужди на самия човек с увреждане и няма никаква връзка с неговите социални роли. Няма как да му дадем повече часове лична помощ, за да бъде този човек с увреждане родител например. Като се замисля – май е същото и с ходенето на работа. Това е така, защото ние не очакваме хората с увреждания да са родители, роднини, граждани или да ходят на работа.
И ако държавата не очаква хората с увреждания да имат различни социални роли, толкова по-малко тя е в състояние да си представи, че те могат да имат чувство за лично пространство, усещане за интимност, нужда от любов, да не говорим за сексуални потребности.
В степента, в която човек с увреждане може да е самостоятелен, той може да се погрижи по един или друг начин и за интимните си потребности. Но колкото повече зависи от чужда помощ, толкова повече най-личната част от живота му е в ръцете на хора, които може дори да не си дават сметка за нея.
В България грижата за хора с увреждания се предоставя основно по два начина.
Ако човекът живее в домашна среда, има право на личен асистент. В общия случай тази роля поема или майката, или друг близък роднина, но понякога се възлага и на външни лица. За 2025 г. базовата заплата на личните асистенти е 1526 лв. на месец за 8-часов работен ден. На практика обаче работното време е твърде условно, защото, ако например някой не може сам да отиде до тоалетната, той може да има нужда от помощ по всяко време на денонощието.
Вторият вариант е, ако човекът с увреждане е в институция. В този случай грижите се поемат от персонала на съответната социална услуга, както се наричат подобни места.
Интимност и увреждания в домашна среда
По времето на пубертета здравите хора започват да се еманципират емоционално от родителите си, а с пълнолетието и постигането на икономическа самостоятелност вече могат да заживеят изцяло свой живот. И този живот може да е в противоречие с принципите, ценностите или желанията на родителите им.
Ако обаче сте с увреждане, в резултат на което зависите от чужда помощ, е доста вероятно да нямате шанс за еманципация. Интимните ви нужди може да останат изцяло незабелязани покрай полагането на физически грижи и търчането по институции, пред които отново и отново трябва да се доказва здравословното ви състояние. Особено ако за хората, които се грижат за вас, сексуалните теми са нещо срамно.
Не вярвах, че някога ще целуна момче, но се упражнявах – целувах си ръката, дланта, пробвах как е с език. Целувах манекените от списанията. […] Момичешки глупости, по цял ден бях сама вкъщи и не знаех какво да правя…
Това са думи на респондентка в изследването на Венелин Стойчев и Надежда Денева. Друга споделя, че не е знаела какво е менструация, когато е дошъл първият ѝ цикъл, и е помислила, че става дума за влошаване на състоянието ѝ. Такъв опит имат и здрави жени с по-консервативни родители, за които подобни теми са табу. Една от интервюираните обаче разказва за своя приятелка, която едва на 50-тина годишна възраст открила мастурбацията – нещо, което повечето здрави деца започват да практикуват от ранна възраст:
И тя ми казва, че ще ми издаде някаква много важна тайна, но да не казвам на никого. И се чудя каква ли е пък тази тайна, дето аз да не я знам, като сме приятелки от хиляда години и всичко си споделяме. А тя сто пъти ме накара да се закълна, че няма да казвам на никого. И след тези увещания накрая ми сподели, че ѝ е хубаво, когато се пипа там долу. Викам ѝ: „Здрасти ма, това се казва мастурбация, на всички ни е хубаво!“ А нея я е срам, че майка ѝ ѝ е личен асистент и ще разбере. И на мен главата ми не може да го проумее – да станеш на петдесет години, за да откриеш мастурбацията и да те е срам от майка ти… В кой век живеем…
Много хора с увреждания не получават възможност да имат интимен партньор или сексуални контакти – не защото физически или умствено не са способни на това, а понеже на личните им асистенти не им минава през ума, че човекът, за когото се грижат, може да има такива потребности. Или ако им минава, смятат за неприлично да се занимават с логистиката. Или пък за тях това са допълнителни ангажименти, които биха предпочели да си спестят.
Други имат пълноценен интимен живот, някои – дори семейства и деца. Но това зависи от личностния хоризонт, добрата воля и възможностите на личните им асистенти.
Но ако нуждаещият се от грижа е с хомосексуална ориентация, а личният му асистент, който в повечето случаи е майката, е с хомофобски разбирания, физическите измерения на споделената интимност се превръщат в недостижим мираж.
Когато хората с увреждания са в състояние да ползват самостоятелно интернет, това за тях е важен отдушник, възможност за социални контакти, виртуална интимност, както и за създаване на желана идентичност:
Интернет беше моето спасение. Осъзнах, че там мога да бъда каквато си искам. Не съм лъгала хората нарочно, ама никой не се представя във форумите със „Здрасти, аз съм саката и съм на количка“.
Интимност и увреждания в специализираните институции
Авторите на доклада разглеждат отношението към хората с увреждания в т.нар. домове през призмата на Мишел Фуко за дисциплинарните институции, като каквито той определя казармата, психиатрията, болницата и затвора. Участник в мониторингова програма за правата на хората с увреждания, интервюиран в изследването, оприличава клиентите на тези социални услуги на „безполови същества, не можеш да разбереш кой е мъж и кой е жена – всичките са остригани, всичките са с едни дълги нощници и бродят като призраци из двора“.
По отношение на живеещите в такива „домове“ думата „потребител“ съдържа особен цинизъм. Защото отношението към един потребител е свързано със стремеж към удовлетворяването на личните му потребности, докато в институциите хората с увреждания са сведени до физиологията си. Експерт в областта на хората с увреждания обяснява манталитета на персонала на домовете така:
Това са едни не лоши, но семпли женици от село, които смятат, че са си свършили работата, ако потребителите им са нахранени, ако са измити, ако им е изчистено. Те просто не могат да видят повече от това. Все едно им е дали се грижат за наранена сърничка, или за човек с увреждане.
В такава среда не може да се очаква уважение към човешката неприкосновеност или допускане, че един човек с увреждане може да има нужда от лично пространство или да изпитва срам. Интервюираният експерт описва случай на момиче с детска церебрална парализа, което не може да говори. Хора от персонала коментират, че момичето става агресивно, когато му сменят памперса, без да отчитат факта, че те правят това пред погледа на момчетата в дома:
Смъкват ѝ гащите, всичко ѝ се вижда от другите младежи, половите ѝ… Беше толкова дивашко, но никой дори и не си помисляше, че това може да е някакъв проблем… Третират ги като малки деца – ако имат памперс, значи ги смятаме за бебетата, не очакваме, че вече разбират, че вече се срамуват…
По същия начин персоналът на тези институции не допуска, че обитателите – дори тогава, когато са в интимна връзка или в брак – могат да имат потребност от любов и личен живот. Интервюираният експерт на мониторингова програма разказва за случай в един смесен дом, тоест за хора от двата пола. В него имало мъж и жена, които са заедно. Но служителите решили да разделят потребителите с психически увреждания от тези с физически. И понеже мъжът бил с лека умствена изоставеност, разделили влюбените насила:
Ние бяхме на посещение и мъжът се оказа избягал. И питаме персонала къде е, а те умират от смях. Оказа се, че той просто всеки ден тръгва пеша по пътя към съседния град, където е жена му. Питам какво го правят, щом знаят къде е, разрешават ли им да се видят. А те се смеят: „Да бе, ще му разрешим! Намираме го по пътя и го връщаме обратно тук, разбира се.“
В домовете, които не са смесени, хомосексуалните отношения са обичайна практика. Както казва един от респондентите, социален работник:
Ти може и да не си лесбийка, но само това е материалът, дето викаше Бойко [Борисов – б.а.]. То е като в казармата, като в затвора – нямаш избор.
В институциите за хора с увреждания сексуалната експлоатация не е изключение. В доклада се описва и случай, в който управителката на едно защитено жилище фактически си присвоява бебе, чиято майка е млада жена с лека форма на умствено увреждане, а бащата е под частично запрещение.
Как е в други страни
Когато на хората с увреждания се гледа като на човешки същества, се създават условия, в които те в максимална степен да могат да имат нормален личен живот, сексуални контакти, да създават семейства.
В някои западноевропейски държави социалното осигуряване покрива сексуални услуги за хора, които поради естеството на уврежданията си трудно могат да си намерят интимен партньор. И има хора, специализирани в предоставянето на такива услуги.
Никога не съм си представяла, че някой ден ще правя секс. Камо ли че ще се омъжа, ще имам съпруг и дете. Никога, беше немислимо отвъд въображението…
Интервюираната жена, която казва това, все пък създава семейство. Но не в България, а във Великобритания. Ходи и на работа. И споделя:
В Англия не мога да им обясня какво е това ТЕЛК, как това е по-важно от паспорта ми. Колегите ми там просто недоумяват…
Друга респондентка има приятелка в чужбина, омъжена и с три деца. Както и личен асистент, който я подготвя за секс с мъжа ѝ и помага в отглеждането на децата.
Възприемането на хората с увреждания като равноценни не би могло да се прилага само от институциите, без да се споделя и от достатъчно членове на обществото.
„Пролетно тайнство“ е испански филм за млада жена с консервативно възпитание, която решава да предоставя сексуални услуги на мъж с тежко увреждане, който е почти неподвижен. Прави го не за парите, а от емпатия – защото общуването с мъжа ѝ помага да си даде сметка какво е да имаш потребност, която не си в състояние да задоволиш.
И ако този филм е художествена измислица, германската обществена медия WDR представя в документална поредица как хора с различни увреждания търсят любов (първа, втора, трета и четвърта част). Помагат им и родителите, и социалната система, и цялата публична среда – всичко заедно прави възможно те да имат пълноценен живот – и социален, и интимен.
А в България любовните и сексуалните потребности на хората с увреждания, нуждата им от интимност и от лично пространство ще бъдат „десетата дупка на кавала“ дотогава, докато продължават да бъдат възприемани като пасивни обекти на грижа. А не като личности с човешко достойнство.
Why we domesticated chickens.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=udkpHN1nkgs
Sail Physics
Post Syndicated from xkcd.com original https://xkcd.com/3090/
Continue to take control over your code with Amazon Q Developer’s new context features
Post Syndicated from Eva Knight original https://aws.amazon.com/blogs/devops/continue-to-take-control-over-your-code-with-amazon-q-developers-new-context-features/
In this blog post, I explore Amazon Q Developer’s latest enhancements to the IDE chat experience including increased context control, chat history and other conversation management features. On March 11th, 2025, my colleague published Take control of your code with Amazon Q Developer’s new context features detailing several improvements to the chat experience within VS Code. These included increased context transparency, the ability to select specific files or folders as context, prompt libraries for reusing prompts across conversations and projects, and project rules to help enforce coding standards and best practices across your teams.
Since then, Amazon Q Developer released additional features in VS Code to help provide users with more control over their conversations and enhance their ability to maintain development context across longer periods. These new capabilities make your interactions with Amazon Q Developer not just more efficient, but also more contextual and persistent—helping you maintain your development flow, even when work spans hours or days. Now, let’s jump in and explore some of the new features available today.
Conversation persistence
We’ve all been there—you’re deep in conversation with Amazon Q Developer, maybe you’re debugging an authentication problem, optimizing a complex database query, or designing a new API structure. You and Amazon Q Developer have been going back and forth, uncovering insights and piecing together solutions.
Then reality intervenes. You close your IDE to focus on another task, step away for a meeting, or maybe update your computer. When you finally return to your IDE, ready to dive back in, you’re met with a blank chat window. All that context, all those valuable exchanges—gone. You find yourself trying to reconstruct your train of thought, wasting precious time and momentum.
Amazon Q Developer now preserves your conversations across your IDE sessions. Instead of starting from scratch each time you open the IDE, you can now come back to your conversation and pick up right where you left off.
Conversation History Search
It isn’t just after a closed IDE session or coming back to your computer after a long-weekend that you want Amazon Q Developer to remember what you have been working on. Sometimes you need to reference a previous solution — maybe Amazon Q Developer gave you some good advice on optimizing your database queries that you want to use elsewhere, or maybe you decided to work on some front-end components so you could have fresh eyes for the API performance issue you’ve been working at.
Now, you can access your previous conversations with Amazon Q Developer by clicking on the search icon in the top right corner of your chat window. You can quickly locate specific discussions by typing keywords into the search bar, then either review the previous exchange or continue the conversation where you left off.

Fig 1 – View chat history feature in the Amazon Q Developer VS Code chat interface.
Conversation Export
But what if you need to share these insights with a teammate or want to keep a local record for future reference? You can now easily export your chat sessions as markdown files, preserving all the valuable information for offline use or collaboration. To do this, click the export button located directly to the right of the chat history button. Alternatively, when browsing your chat history, you can export individual sessions by clicking the three dots on the right side of each conversation entry.

Fig 2 – Export chat feature in the Amazon Q Developer VS Code chat interface.
Increasing your control over context
Last July, we announced the ability to use @workspace in your chat session to provide comprehensive context across your entire application within the IDE. To provide more control over what Amazon Q Developer uses as context, earlier this year we released the ability to use the @ symbol in the chat to include specific folders or files as context for your conversation.
We are now taking your level of control one step further to allow you to use @ in your conversation to find and include classes, functions, and global variables into the input context. Rather than leaving it up to Amazon Q to determine the relevant files, folders, or functions for your request, you can continue to be more explicit with your request to receive the most relevant and accurate responses.

Fig 3 – Context selection in Amazon Q Developer chat, using “@” to show relevant folders, files, functions.
Conclusion
Amazon Q Developer is continuing to evolve its features that help put developers in control of their coding experience. By offering conversation persistence, history search, and export capabilities, Amazon Q Developer works to create continuity that allows developers to maintain their momentum across sessions and easily revisit past solutions. The expanded context control features empower developers to fine-tune their interactions with Amazon Q Developer, and receive more precise and relevant responses.
To get started with these features in VS Code, visit the Amazon Q Developer Getting Started guide and explore the full range of capabilities that can help you create impressive software more efficiently.