Post Syndicated from Explosm.net original https://explosm.net/comics/addiction-2
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/addiction-2
New Cyanide and Happiness Comic
Post Syndicated from xkcd.com original https://xkcd.com/3009/
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=jMU7TLe5aDo
Post Syndicated from Arvind Mahesh original https://aws.amazon.com/blogs/big-data/amazon-opensearch-service-announces-standard-and-extended-support-dates-for-elasticsearch-and-opensearch-versions/
Amazon OpenSearch Service supports 19 versions of Elasticsearch opensource, and 11 versions of OpenSearch. Over the years, we have added several stability, resiliency, and security features to recent engine versions, helping customers derive better value from OpenSearch Service. As software versions grow older, we need to make sure that these versions continue to meet high security and compliance standards. Many of the legacy versions supported on OpenSearch Service, such as Elasticsearch versions 1.5 and 2.3, depend on third-party dependencies that are no longer actively supported. By moving to the latest engine versions, customers can derive maximum benefit from the new features, improved price-performance, and security improvements we make to OpenSearch.
Today, we’re announcing timelines for end of Standard Support and Extended Support for legacy Elasticsearch versions up to 6.7, Elasticsearch versions 7.1 through 7.8, OpenSearch versions from 1.0 through 1.2, and OpenSearch versions 2.3 through 2.9 available on Amazon OpenSearch Service. Versions that are under Standard Support receive regular bug fixes and security fixes, and versions in Extended Support receive critical security fixes and operating system patches for an additional flat fee per normalized instance hour. With Extended Support, we want to make sure that our customers continue to receive critical security fixes for an adequate time, while they plan to upgrade to more recent engine versions. For more details on Extended Support please see the FAQs.
See Table 1 that follows for end of Standard Support and Extended Support dates for legacy Elasticsearch versions available on OpenSearch Service. We recommend that customers running Elasticsearch versions upgrade to the latest OpenSearch versions. All Elasticsearch versions will receive at least 12 months of Extended Support, and version 5.6 will receive 36 months of Extended Support. After Extended Support ends for a version, domains running the specific version will not receive bug fixes or security updates.
| Software version | End of Standard Support | End of Extended Support |
| Elasticsearch versions 1.5 and 2.3 | 11/7/2025 | 11/7/2026 |
| Elasticsearch versions 5.1 to 5.5 | 11/7/2025 | 11/7/2026 |
| Elasticsearch version 5.6 | 11/7/2025 | 11/7/2028 |
| Elasticsearch versions 6.0 to 6.7 | 11/7/2025 | 11/7/2026 |
| Elasticsearch version 6.8 | Not announced | Not announced |
| Elasticsearch versions 7.1 to 7.8 | 11/7/2025 | 11/7/2026 |
| Elasticsearch version 7.9 | Not announced | Not announced |
| Elasticsearch version 7.10 | Not announced | Not announced |
For OpenSearch versions running on Amazon OpenSearch Service, we will provide at least 12 months of Standard Support after the end of support date for the corresponding upstream open source OpenSearch version, or 12 months of Standard Support after the release of the next minor version on OpenSearch Service, whichever is longer. All OpenSearch versions will receive at least 12 months of Extended Support after the end of Standard Support date. For more details, check the open source OpenSearch maintenance policy.
See Table 2 that follows for end of Standard Support and Extended Support dates for various OpenSearch versions available on OpenSearch Service. For future updates on versions in Standard Support and Extended Support, follow supported versions.
| Software Version | End of Standard Support | End of Extended Support |
| OpenSearch versions 1.0 to 1.2 | 11/7/2025 | 11/7/2026 |
| OpenSearch version 1.3 | Not announced | Not announced |
| OpenSearch versions 2.3 to 2.9 | 11/7/2025 | 11/7/2026 |
| OpenSearch versions 2.11 and higher versions | Not announced | Not announced |
Upgrading OpenSearch Service domains: We recommend that you update your domains to the latest available OpenSearch version to derive maximum value out of OpenSearch Service. Minor version upgrades on OpenSearch tend to be seamless because they don’t contain breaking changes, and we recommend moving to the latest minor version, or a version for which end of support has not yet been announced. For example, if you are on OpenSearch version 1.2, you can move to OpenSearch version 1.3, because it’s the last minor version of the 1.x series and because presently it continues to be supported by the open source community and AWS. If you want to choose an Elasticsearch version, and you are running an older 6.x or 7.x version, you can move to version 6.8, or 7.10.
There are various ways to upgrade your cluster to a newer version, and the steps vary depending on the version your domain is running and the version you want to upgrade to. See Upgrading OpenSearch Service domains for detailed instructions on upgrading your domain to a new version. You can also use the Migration Assistant for Amazon OpenSearch Service for upgrading to newer versions
Calculating Extended Support charges: Domains running versions under Extended Support will be charged a flat additional fee per normalized instance hour (NIH). For example, $0.0065 per NIH in the US East (North Virginia) AWS Region. See the pricing page for exact pricing by Region.
NIH is computed as a factor of the instance size (for example, medium or large), and the number of instance hours. For example, if you’re running an m7g.medium.search instance for 24 hours in the US EAST (North Virginia) Region, which is priced at $0.068 per instance hour (on-demand), you will typically pay $1.632 ($0.068×24). If you’re running a version that is in Extended Support, you will pay an additional $0.0065 per NIH, which is computed as $0.0065 x 24 (number of instance hours) x 2 (size normalization factor, which is 2 for medium-sized instances), which comes to $0.312 for Extended Support for 24 hours. The total amount that you will pay for 24 hours will be a sum of the standard instance usage cost and the Extended Support cost, which is $1.944 ($1.632+$0.312, excluding storage cost). The following table shows the normalization factor for various instance sizes in OpenSearch Service.
| Instance size | Normalization Factor |
| nano | 0.25 |
| micro | 0.5 |
| small | 1 |
| medium | 2 |
| large | 4 |
| xlarge | 8 |
| 2xlarge | 16 |
| 4xlarge | 32 |
| 8xlarge | 64 |
| 9xlarge | 72 |
| 10xlarge | 80 |
| 12xlarge | 96 |
| 16xlarge | 128 |
| 18xlarge | 144 |
| 24xlarge | 192 |
| 32xlarge | 256 |
We add new capabilities across various vectors to the latest OpenSearch versions, which include new features, performance and resiliency improvements, and security improvements. We recommend that you update to recent OpenSearch versions to get the most benefit out of OpenSearch Service. For any questions on Standard and Extended Support options, see the FAQs. For further questions, contact AWS Support.
 Arvind Mahesh is a Senior Manager-Product at Amazon Web Services for Amazon OpenSearch Service. He has close to two decades of technology experience across a variety of domains such as Analytics, Search, Cloud, Network Security, and Telecom.
 Kuldeep Yadav is a Senior Technical Program Manager at Amazon Web Services who is passionate about driving innovation and complex problem solving. He works closely with teams and customers in ensuring operational excellence and achieving more with less. Outside of work he enjoys trekking and all sports
 Jon Handler is a Senior Principal Solutions Architect at Amazon Web Services based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have search and log analytics workloads that they want to move to the AWS Cloud. Prior to joining AWS, Jon’s career as a software developer included 4 years of coding a large-scale, ecommerce search engine. Jon holds a Bachelor of the Arts from the University of Pennsylvania, and a Master of Science and a PhD in Computer Science and Artificial Intelligence from Northwestern University.
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-express-brokers-for-amazon-msk-to-deliver-high-throughput-and-faster-scaling-for-your-kafka-clusters/
Today, we’re announcing the general availability of Express brokers, a new broker type for Amazon Managed Streaming for Apache Kafka (Amazon MSK). It’s designed to deliver up to three times more throughput per-broker, scale up to 20 times faster, and reduce recovery time by 90 percent as compared to Standard brokers running Apache Kafka. Express brokers come preconfigured with Kafka best practices by default, support Kafka APIs, and provide the same low latency performance that Amazon MSK customers expect, so they can continue using existing client applications without any changes.
Express brokers provide improved compute and storage elasticity for Kafka applications when using Amazon MSK provisioned clusters. Amazon MSK is a fully-managed AWS service that makes it easier for you to build and run highly available and scalable applications based on Apache Kafka.
Let’s dive deeper into some of the key features that Express brokers have and the benefits they provide:
m7g.16xl Standard brokers safely handling 154 MBps ingress. Express brokers use opinionated settings and resource isolation, enabling m7g.16xl size instances to safely manage up to 500 MBps ingress without compromising performance or availability during cluster events.You have choice options in Amazon MSK depending on your workload and preference:
| MSK provisioned | MSK Serverless | ||
| Standard brokers | Express brokers | ||
| Configuration range | Most flexible | Flexible | Least flexible |
| Cluster rebalancing | Customer managed | Customer managed but up to 20x faster |
MSK managed |
| Capacity management | Yes | Yes (compute only) | No |
| Storage management | Yes | No | No |
Express brokers lower costs, provide higher resiliency, and lower operational overhead, making them the best choice for all Kafka workloads. If you prefer to use Kafka without managing any aspect of its capacity, its configuration, or how it scales, then you can choose Amazon MSK Serverless. This provides a fully abstracted Apache Kafka experience that eliminates the need for any infrastructure management, scales automatically, and charges you on a pay-per-use consumption model that doesn’t require you to optimize resource utilization.
Getting started with Express brokers in Amazon MSK
To get started with Express brokers, you can use the Sizing and Pricing worksheet that Amazon MSK provides. This worksheet helps you estimate the cluster size you’ll need to accommodate your workload and also gives you a rough estimate of the total monthly cost you’ll incur.
The throughput requirements of your workload are the primary factor in the size of your cluster. You should also consider other factors, such as partition and connection count to arrive at the size and number of brokers you’ll need for your cluster. For example, if your streaming application needs 30 MBps of data ingress (write) and 80 MBps data egress (read) capacity, you can use three express.m7g.large brokers to meet your throughput needs (assuming the partition count for your workload is within the maximum number of partitions that Amazon MSK recommends for an m7g.large instance).
The following table shows the recommended maximum ingress, egress, and partition counts per instance size for sustainable and safe operations. You can learn more about these recommendations in the Best practices section of Amazon MSK Developer Guide.
| Instance size | Ingress (MBps) | Egress (MBps) |
express.m7g.large |
15.6 | 31.2 |
express.m7g.4xlarge |
124.9 | 249.8 |
express.m7g.16xlarge |
500.0 | 1000.0 |
Once you have decided the number and size of Express brokers you’ll need for your workload, go to the AWS Management Console or use the CreateCluster API to create an Amazon MSK provisioned cluster.
When you create a new cluster on the Amazon MSK console, in the Broker type option, choose Express brokers and then select the mount of compute capacity that you want to provision for the broker. As you can see in the screen shot, you can use Apache Kafka 3.6.0 version and Graviton-based instances for Express brokers. You don’t need to preprovision storage for Express brokers.

You can also customize some of these configurations to further fine-tune the performance of your clusters according to your own preferences. To learn more, visit Express broker configurations in the Amazon MSK developer guide.
To create an MSK cluster in the AWS Command Line Interface (AWS CLI), use the create-cluster command.
aws kafka create-cluster \
    --cluster-name "channy-express-cluster" \
    --kafka-version "3.6.0" \
    --number-of-broker-nodes 3 \
    --broker-node-group-info file://brokernodegroupinfo.json
A JSON file named brokernodegroupinfo.json specifies the three subnets over which you want Amazon MSK to distribute the broker nodes.
{
    "InstanceType": "express.m7g.large",
    "BrokerAZDistribution": "DEFAULT",
    "ClientSubnets": [
        "subnet-0123456789111abcd",
        "subnet-0123456789222abcd",
        "subnet-0123456789333abcd"
    ]
}
Once the cluster is created, you can use the bootstrap connection string to connect your clients to the cluster endpoints.

With Express brokers, you can scale vertically (changing instance size) or horizontally (adding brokers). Vertical scaling doubles throughput without requiring partition reassignment. Horizontal scaling adds brokers in sets of three and and allows you to create more partitions, but it requires partition reassignment for new brokers to serve traffic.
A major benefit of Express brokers is that you can add brokers and rebalance partitions within minutes. On the other hand, rebalancing partitions after adding Standard brokers can take several hours. The graph below shows the time it took to rebalance partitions after adding 3 Express brokers to a cluster and reassigning 2000 partitions to each of the new brokers.

As you can see, it took approximately 10 minutes to reassign these partitions and utilize the additional capacity of the new brokers. When we ran the same experiment on an equivalent cluster comprising of Standard brokers, partition reassignment took over 24hours.
To learn more about the partition reassignment, visit Expanding your cluster in the Apache Kafka documentation.
Things to know
Here are some things you should know about Express brokers:
Now available
The Express broker type is available today in the US East (Ohio), US East (N. Virginia), US West (Oregon), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Europe (Frankfurt), and Europe (Ireland), and Europe (Stockholm) Regions.
You pay an hourly rate for Apache Kafka broker instance usage (billed at one-second resolution) for Express brokers, with varying fees depending on the size of the broker instance and active brokers in your MSK clusters. You also pay a per-GB rate for data written to an Express broker (billed at per-byte resolution). To learn more, visit the Amazon MSK pricing page.
Give Express brokers for Amazon MSK a try in the Amazon MSK console. For more information, visit the Amazon MSK Developer Guide and send feedback to AWS re:Post for Amazon MSK or through your usual AWS support contacts.
— Channy
Post Syndicated from Raghu Kuppala original https://aws.amazon.com/blogs/big-data/write-queries-faster-with-amazon-q-generative-sql-for-amazon-redshift/
Amazon Redshift is a fully managed, AI-powered cloud data warehouse that delivers the best price-performance for your analytics workloads at any scale. Amazon Q generative SQL brings the capabilities of generative AI directly into the Amazon Redshift query editor. Amazon Q generative SQL for Amazon Redshift was launched in preview during AWS re:Invent 2023. With over 85,000 queries executed in preview, Amazon Redshift announced the general availability in September 2024.
Amazon Q generative SQL for Amazon Redshift uses generative AI to analyze user intent, query patterns, and schema metadata to identify common SQL query patterns directly within Amazon Redshift, accelerating the query authoring process for users and reducing the time required to derive actionable data insights. It provides a conversational interface where users can submit queries in natural language within the scope of their current data permissions. Generative SQL uses query history for better accuracy, and you can further improve accuracy through custom context, such as table descriptions, column descriptions, foreign key and primary key definitions, and sample queries. Custom context enhances the AI model’s understanding of your specific data model, business logic, and query patterns, allowing it to generate more relevant and accurate SQL recommendations. It enables you to get insights faster without extensive knowledge of your organization’s complex database schema and metadata.
Within this feature, user data is secure and private. Your data is not shared across accounts. Your queries, data and database schemas are not used to train a generative AI foundational model (FM). Your input is used as contextual prompts to the FM to answer only your queries.
In this post, we show you how to enable the Amazon Q generative SQL feature in the Redshift query editor and use the feature to get tailored SQL commands based on your natural language queries. With Amazon Q, you can spend less time worrying about the nuances of SQL syntax and optimizations, allowing you to concentrate your efforts on extracting invaluable business insights from your data.
At a high level, the feature works as follows:
The following diagram illustrates this workflow.

Your content processed by generative SQL is not stored or used by AWS for service improvement.
Amazon Q generative SQL uses a large language model (LLM) and Amazon Bedrock to generate the SQL query. AWS uses different techniques, such as prompt engineering and Retrieval Augmented Generation (RAG), to query the model based on your context:
Amazon Q generative SQL is conversational, and you can ask it to refine a previously generated query.
In the following sections, we demonstrate how to enable the generative SQL feature in the Redshift query editor and use it to generate SQL queries using natural language.
To get started, you need an Amazon Redshift Serverless endpoint or an Amazon Redshift provisioned cluster. For this post, we use Redshift Serverless. Refer to Easy analytics and cost-optimization with Amazon Redshift Serverless to get started.
If you’re using the feature for the first time, you need to enable the Amazon Q generative SQL feature in the Redshift query editor.
To enable the feature, complete the following steps:

You can also choose Query Editor V2 in the navigation pane of the Amazon Redshift console.
When you open the Redshift query editor, you will see the new icon for Amazon Q next to the database dropdown menu on the top of the query editor console.

If you choose the Amazon Q icon, you will see the message “Amazon Redshift query editor V2 now supports generative SQL functionality. Contact your administrator to activate this feature in Settings.” If you’re not the administrator, you need to work with the account administrator to enable this feature.
Amazon Q generative SQL is personalized to your database and, based on the updates or conversations you have had with the feature, will apply those learnings to other user conversations who connect to the same database with their own credentials. In the generative SQL settings, you can see the instructions to grant the sys:monitor role to a user or role.

You will receive a confirmation that the Amazon Q generative SQL settings have been successfully updated.

The Redshift query editor comes with sample data and SQL notebooks that you can load into a sample database and corresponding schema. For this post, we use TPC-DS for a decision support benchmark.
We start by loading the TPC-DS data into the Redshift database. When you load this data, the schema tpcds is updated with sample data. We also use the provided notebooks with the tpcds schema to run queries to build a query history.
Complete the following steps:
sample_data_dev database to view the sample databases available for running the generative SQL feature.tpcds schema and choose Open sample notebooks.

In a few seconds, you will see the notification that the database sample_data_dev is created successfully and tpcds sample data is loaded successfully. Two sample notebooks for the schema are also generated.

This will take a few minutes to run and will establish a query history for the tpcds data.

This step is not mandatory for using the feature for your organization’s data warehouse.
Now that the Amazon Q generative SQL feature is enabled and ready for use, open a new notebook and choose the Amazon Q icon to open a chat pane in the Redshift query editor.

Amazon Q generative SQL is personalized to your schema. It uses metadata from database schemas to improve the SQL query suggestions. Optionally, administrators can allow the use of the account’s query history to further improve the generated SQL. This can be enabled by running the following GRANT commands to provide access to your query history to other roles or users:
This optional step allows users to make query monitoring history available to other users connected to the same database.
Let’s get started with some query examples.
sample_data_devThis generates a SQL query. Amazon Q generative SQL is also personalized to your data domain. You will notice that it joins to the Store table to retrieve store_name.

Our query runs successfully and shows that the store able has the most sales.
able. You can ask this question “What was the unique identifier of the top selling item for the store ‘able’?”
The results show the top selling item. However, the query didn’t filter on the year.
able in 1998. Instead of repeating the whole question again, you can simply ask “Can you filter by the year 1998?”
Now we have the top selling item for store able for 1998.

Amazon Q added the join to the item table and the query ran successfully.
Now that we have done some basic queries, let’s do some deeper analysis.

The answer is correct, but let’s ask a follow-up to include the state.

This answer looks good; you can also add an ORDER BY clause if you want the data sorted or ask Amazon Q to add that.
So far, we have only been looking at store_sales data. The TPC-DS data contains data for other sales channels, including web_sales and catalog_sales.

Let’s dive deeper into some other capabilities of Amazon Q generative SQL.
User3 and granted the sys:monitor
User3, let’s ask the original question of “What are the top 10 stores in sales in 1998?”
Amazon Q generative SQL is able to use the query history and provide SQL recommendations for User3’s prompts because they have access to the system metadata provided through the role sys:monitor.
Amazon Q generative SQL has built-in safety features to warn if a generated SQL statement will modify data and will only run based on user permissions. To test this, let’s ask Amazon Q to “delete data from web_sales table.”

Amazon Q gives a message “I detected that this query changes your database. Only run this SQL command if that is appropriate.”
Now, still logged in as User3, choose Run to try to delete the web_sales data.

As expected, User3 gets a permission denied error, because they don’t have the necessary privileges to delete the web_sales table.
Custom context is a feature that allows you to provide domain-specific knowledge and preferences, giving you fine-grained control over the SQL generation process.
The custom context is defined in a JSON file, which can be uploaded by the query editor administrator or can be added directly in the Custom context section in Amazon Q generative SQL settings.


This JSON file contains information that helps Amazon Q generative SQL better understand the specific requirements and constraints of your domain, enabling it to generate more targeted and relevant SQL queries.
By providing a custom context, you can influence factors such as:
The custom context feature empowers you to take a more active role in shaping the SQL generation process, leading to SQL queries that are better suited to your data and business requirements.
In this post, we use the BIRD (BIg Bench for LaRge-scale Database Grounded Text-to-SQL Evaluation) sample dataset, consisting of three tables. BIRD represents a pioneering, cross-domain dataset that examines the impact of extensive database contents on text-to-SQL parsing.
You can load the following BIRD sample dataset into your Redshift data warehouse to experiment with using custom contexts.
For this post, we demonstrate with three custom contexts.
TablesToInclude specifies a set of tables that are considered for SQL generation. This field is crucial when you want to limit the scope of SQL queries to a defined subset of available tables. It can help optimize the generation process by reducing unnecessary table references.
Let’s ask Amazon Q “List the distinct translated title and the set code of all cards translated into Spanish.”

This SQL unnecessarily uses the public.cards table. The public.set_translations table contains the data sufficient to answer the question.
We can add the following TablesToInclude custom context JSON:
After adding the custom context, the unwanted joins are eliminated and the correct SQL is generated.

ColumnAnnotations allows you to provide metadata or annotations specific to individual columns in your data tables. These annotations can offer valuable insights into the definitions and characteristics of the columns, which can be beneficial in guiding the SQL generation process.
Let’s ask Amazon Q to “Show me the unconverted mana cost and name for all the cards created by Rob Alexander.”

The generated SQL points to the column convertedmanacost, which doesn’t give a value for unconverted mana cost. The manacost column gives the unconverted mana cost.
Let’s add this using ColumnAnnotations in the custom context JSON:
After the custom context is added, the correct SQL gets generated.

CuratedQueries provides a set of predefined question and answer pairs. In this set, the questions are written in natural language and the corresponding answers are the SQL queries that should be generated to address those questions.
These examples serve as a valuable reference point for Amazon Q generative SQL, helping it understand the types of queries it is expected to generate. You can guide Amazon Q generative SQL with the desired format, structure, and content of the SQL queries it should produce.
Let’s ask Amazon Q “List down the name of artists for cards in Chinese Simplified.”

Although the join key multiverseid exists, it is not correct.
Let’s add the following using CuratedQueries in the custom context JSON:
After the custom context is added, the correct SQL gets generated.

In this section, we discuss the supporting features available with Amazon Q generative SQL feature for Redshift query editor:
Amazon Q generative SQL allows you to provide feedback on the SQL queries it generates, helping improve the quality and relevance of the SQL over time. This feedback mechanism is accessible through the Amazon Q generative SQL interface, where you can indicate whether the generated SQL was helpful or not.
If you find the generated SQL to not be helpful, you can categorize the feedback into the following areas:
In addition to selecting the appropriate feedback category, you can also provide free text comments to elaborate on the specific issues or inaccuracies you found in the generated SQL. This additional information can be valuable for Amazon Q to better understand the problems and make improvements.
By actively providing this feedback, you play a crucial role in refining the generation capabilities of Amazon Q generative SQL. The feedback you provide helps the service learn from its mistakes, leading to more accurate and relevant SQL queries that better meet your needs over time.
This feedback loop is an important part of Amazon Q generative SQL’s continuous improvement, because it allows the service to adapt and evolve based on your specific requirements and use cases.

The Regenerate SQL option will prompt Amazon Q to generate a new SQL query based on the same natural language prompt, using its learning and improvement capabilities to provide a potentially better-suited response.

By choosing Refresh database, you can instruct Amazon Q generative SQL to re-fetch and update the metadata information about the connected database.
This metadata includes:

To get more accurate SQL recommendations from Amazon Q generative SQL, keep in mind the following best practices:
To avoid incurring future charges, delete the Redshift cluster you provisioned as part of this post.
Amazon Q generative SQL for Amazon Redshift simplifies query authoring and increases productivity by allowing you to express queries in natural language and receive SQL code recommendations. This post demonstrated how the Amazon Q generative SQL feature can accelerate data analysis by reducing the time required to write SQL queries. By using natural language processing and seamlessly converting it into SQL, you can boost productivity without requiring an in-depth understanding of your organization’s database structures. Importantly, the robust security measures of Amazon Redshift remain fully enforced, and the quality of the generated SQL continues to improve over time by enabling query history sharing across users.
Get started on your Amazon Q generative SQL journey with Amazon Redshift today by implementing the solution in this post or by referring to Interacting with Amazon Q generative SQL. For pricing information, refer to Amazon Q generative SQL pricing. Also, please try other Redshift generative AI features such as Amazon Redshift Integration with Amazon Bedrock and Amazon Redshift Serverless AI-driven scaling and optimization.
 Raghu Kuppala is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.
 Sushmita Barthakur is a Senior Data Solutions Architect at Amazon Web Services (AWS), supporting Enterprise customers architect their data workloads on AWS. With a strong background in data analytics, she has extensive experience helping customers architect and build enterprise data lakes, ETL workloads, data warehouses and data analytics solutions, both on-premises and the cloud. Sushmita is based out of Tampa, FL and enjoys traveling, reading and playing tennis.
 Xiao Qin is a senior applied scientist with the Learned Systems Group (LSG) at Amazon Web Services (AWS). He studies and applies machine learning techniques to solve data management problems. He is one of the developers that build the Amazon Q generative SQL capability.
 Erol Murtezaoglu, a Technical Product Manager at AWS, is an inquisitive and enthusiastic thinker with a drive for self-improvement and learning. He has a strong and proven technical background in software development and architecture, balanced with a drive to deliver commercially successful products. Erol highly values the process of understanding customer needs and problems, in order to deliver solutions that exceed expectations.
 Phil Bates was a Senior Analytics Specialist Solutions Architect at AWS, before retiring, with over 25 years of data warehouse experience.
Post Syndicated from Explosm.net original https://explosm.net/comics/millenials
New Cyanide and Happiness Comic
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/mikrotik-crs304-4xg-in-review-this-is-a-must-have-10gbase-t-marvell-switch/
At $199 or less, the MikroTik CRS304-4XG-IN is finally bringing 10Gbase-T to the masses as the best low power silent switch in its class
The post MikroTik CRS304-4XG-IN Review This is a Must-Have 10Gbase-T Switch appeared first on ServeTheHome.
Post Syndicated from The Hook Up original https://www.youtube.com/watch?v=ClIboELoz74
Post Syndicated from Hang Zuo original https://aws.amazon.com/blogs/big-data/amazon-opensearch-service-launches-the-next-generation-opensearch-ui/
Amazon OpenSearch Service launches a modernized operational analytics experience that can provide comprehensive observability spanning multiple data sources, so that you can gain insights from OpenSearch and other integrated data sources in one place. The launch also introduces OpenSearch Workspaces that provides tailored experience for popular use cases and supports access control, so that you can create a private space for your use case and share it only to your collaborators. With the next-generation user interface (UI), the Discover experience has been improved to simplify interactive analysis, so that you can easily utilize features such as natural language query generation to gain insights from your data.
Multiple Data Source: You might have already used OpenSearch Dashboards to provide an operational analytics experience for your OpenSearch clusters. OpenSearch Dashboards is co-located with a cluster, so that each OpenSearch Dashboards can only work with one cluster. And as you scale up your workload across multiple clusters, there is not a unified experience to analyze your data in one place. In comparison, the next-generation OpenSearch UI is designed to work across multiple OpenSearch clusters to aggregate the comprehensive insights in one place. An OpenSearch application is an instance of the next-generation OpenSearch UI. Currently, OpenSearch applications can be associated with multiple OpenSearch clusters (above version 1.3), Amazon OpenSearch Service Serverless collections, and integrated data sources such as Amazon S3. Each OpenSearch cluster can be associated with multiple OpenSearch applications, in addition to its co-located OpenSearch Dashboards that will remain functional.
Workspace: With workspaces, you can easily create your use case specific contents in a private space and manage the permissions in team collaboration. Workspace provide curated experiences for popular use cases such as Observability, Security Analytics and Search, so that you can find it straightforward to build contents for your use case. Workspace supports collaborator management, so that you can share your workspace only to your intended collaborators, and manage the permissions for each collaborator.
Discover: The improved Discover feature now provides a unified log exploration experience that adds the support for SQL and Piped Processing Language (PPL), in addition to the existing support for DQL and Lucene. Discover features a new data selector to support multiple data sources, a new visual design, query autocomplete and natural language query generation for improved usability. With the enhanced Discover interface, you can now analyze data from multiple sources without switching tools, reducing complexity and improving efficiency.
The following diagram illustrates architecture of the OpenSearch Dashboards.

The following diagram illustrates the next-generation OpenSearch UI architecture.

In the following sections, we discuss the following topics
We’ll demonstrate how these improvements streamline data analysis, foster collaboration, and empower you to extract insights more efficiently across various use cases.
To begin using the next-generation OpenSearch UI, you can first create an application. An application is an instance of the OpenSearch UI (Dashboards), and you have the flexibility to create multiple applications within a single account. To create a new application, complete the following steps:
This page lists all the existing applications under your account in the current AWS region. You can create new application from this page.

This page is the create application workflow. You can specify the application name, enable/disable IDC and define application admins to create an application.

After you configured these settings and created an application, your new OpenSearch application will be ready for you to associate data sources and start using the enhanced UI capabilities.
After you create your new OpenSearch application, the next step is to associate the relevant data sources. This allows you to connect the application to the necessary OpenSearch domains, collections, and other data sources.
You will be presented with a list of all the OpenSearch data sources you have access to, including managed domains and serverless collections.

OpenSearch domains below version v1.3 will not be compatible with the next-generation UI, and will be grayed out in the list. Additionally, if you need to connect to a domain within a virtual private cloud (VPC), you will need to authorize OpenSearch application as a new principal under its security configurations. If you need to connect to a collection within a VPC, you will need to configure its network policy to Private, enable AWS service private access with OpenSearch application.
Your OpenSearch application is now ready to use, with access to the connected data.
To access your new OpenSearch application, you can either choose the application URL or choose Launch application on the application details page. After you’ve successfully logged in either with IAM or IDC, you’ll be directed to the application’s homepage. From here, you can choose to create a new workspace or navigate to an existing one that you have access to.

A workspace is a tailored experience for your use case and team collaboration. There are five types of workspaces: Observability, Security Analytics, Search, Essentials, and Analytics. You can click on the info button to learn more about each workspace type. Existing workspaces will be listed on the homepage. To create a new workspace, complete the following steps:
For this post, we create an Observability workspace named MyWorkspace and associate it with one Amazon OpenSearch Serverless collection and one Amazon OpenSearch Service managed cluster. You can always manage the data sources associated with a workspace, even after it has been created.

After you create your new workspace, you can add users or groups as collaborators. Workspace collaborators are the users you want to invite to work with you in this workspace, and there are three available permission levels for collaborators: admin, read/write, and read-only. Read/write permission allows a collaborator to create, edit and delete the dashboards, visualizations, and saved queries within the workspace, whereas collaborators with read-only access can only view the results. Admin level gives a collaborator the same permissions as you to not only read/write but also update the configurations of the workspace or delete it.
To add collaborators to your workspace, complete the following steps:

If you do not know the ARN of your intended collaborator, follow the instruction to check for their ARN, for example.

The improved navigation in workspaces provides a more contextual and purpose-built interface, ensuring that each workspace includes only the tools and features relevant to its use case. With enhanced clarity and better organization, the new navigation system is tailored to help you find the features you need quickly, improving overall productivity and minimizing time spent searching through menus.

Discover is now revamped to offer improved usability and efficiency. You can access multiple data sources, natural language query generation, a new data selector, and polished design with optimized data density, allowing you to effortlessly navigate and analyze your data:


In this post, we discussed the features of the next-generation OpenSearch UI. These improvements streamline data analytics, foster collaboration, and empower you to extract insights more efficiently across various use cases.
You can create your own OpenSearch UI applications today in the US East (N. Virginia), US West (N. California, Oregon), Asia Pacific (Mumbai, Singapore, Sydney, Tokyo), South America (São Paulo), Europe (Frankfurt, Ireland, London, Paris) and Canada (Central) Regions.
 Hang (Arthur) Zuo is a Senior Product Manager with Amazon OpenSearch Service. Arthur leads the core experience in the next-gen OpenSearch UI and data migration to Amazon OpenSearch Service. Arthur is passionate about cloud technologies and building data products that help users and businesses gain actionable insights and achieve operational excellence.
 Rushabh Vora is a Principal Product Manager for the OpenSearch project of Amazon Web Services. Rushabh leads core experiences in data exploration, dashboards, visualizations, reporting, and data management to help organizations unlock insights at scale. Rushabh is passionate about cloud technologies and building products that enable businesses to make data-driven decisions and achieve operational excellence.
 Sohaib Katariwala is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service based out of Chicago, IL. His interests are in all things data and analytics. More specifically he loves to help customers use AI in their data strategy to solve modern day challenges.
 Arun Lakshmanan is a Search Specialist with Amazon OpenSearch Service based out of Chicago, IL. He works closely with customers on their OpenSearch journey across various use cases including vector search, observability, and security analytics.
 Xenia Tupitsyna is a UX Designer at OpenSearch. She is working on user experiences across security analytics solutions, anomaly detection, alerting, and core dashboards.
Post Syndicated from corbet original https://lwn.net/Articles/997094/
Flexible arrays — arrays that are declared as the final member of a
structure and which have a size determined at run time — have long drawn
the attention of developers seeking to harden the kernel against
buffer-overflow vulnerabilities. These arrays have reliably been a source
of bugs, so anything that can be done to ensure that operations on them
stay within bounds is a welcome improvement. While many improvements,
including the recent counted-by work, have
been made, one of the most difficult cases remains. Now, however,
developers who are interested in using recent compiler bounds-checking
features are trying to get a handle on struct sockaddr.
Post Syndicated from Ritesh Sinha original https://aws.amazon.com/blogs/big-data/accelerate-sql-code-migration-from-google-bigquery-to-amazon-redshift-using-bladebridge/
Accelerating SQL code migration from Google BigQuery to Amazon Redshift can be a complex and time-consuming task. Businesses often struggle to efficiently translate their existing BigQuery code to Amazon Redshift, which can delay critical data modernization initiatives. However, with the right tools and approach, this migration process can be significantly streamlined.
This post explores how you can use BladeBridge, a leading data environment modernization solution, to simplify and accelerate the migration of SQL code from BigQuery to Amazon Redshift. BladeBridge offers a comprehensive suite of tools that automate much of the complex conversion work, allowing organizations to quickly and reliably transition their data analytics capabilities to the scalable Amazon Redshift data warehouse. BladeBridge provides a configurable framework to seamlessly convert legacy metadata and code into more modern services such as Amazon Redshift.
Amazon Redshift is a fully managed data warehouse service offered by Amazon Web Services (AWS). Tens of thousands of customers use Amazon Redshift every day to run analytics, processing exabytes of data for business insights. Whether your growing data is stored in operational data stores, data lakes, streaming data services, or third-party datasets, Amazon Redshift helps you securely access, combine, and share data with minimal movement or copying. Amazon Redshift is built for scale and delivers up to 7.9 times better price performance than other cloud data warehouses.
By using the BladeBridge Analyzer and BladeBridge Converter tools, organizations can significantly reduce the time and effort required to migrate BigQuery code to Amazon Redshift. The Analyzer provides detailed assessments of the complexity and requirements for the migration, and the Converter automates the actual code conversion process, using pattern-based customizable rules to streamline the transition.
In this post, we walk through the step-by-step process of using BladeBridge to accelerate the migration of BigQuery SQL code to Amazon Redshift.
The BladeBridge solution is composed of two key components: the BladeBridge Analyzer and the BladeBridge Converter.
The Analyzer is designed to thoroughly assess the complexities of the existing data environment, in this case, Google BigQuery. After assessment of the source SQL files, it generates a comprehensive report that provides valuable insights into the migration effort. The Analyzer report includes the following:
The Converter is a pattern-based automation tool that streamlines the actual code conversion process from BigQuery to Amazon Redshift. The Converter uses a set of predefined conversion rules and patterns to automatically translate 70–95% of the legacy SQL code. This significantly reduces the manual effort required by developers. The Converter works by doing the following:
The out-of-the-box code handles most conversions. The Converter allows developers to customize the conversion patterns for more complex transformations.
The following is the migration procedure:
The following diagram illustrates these steps.

You need the following prerequisites to implement the solution:
Follow these solution steps:
For SQL data warehouses such as BigQuery, code preparation starts by exporting the SQL files out of the data warehouse solution. If your BigQuery SQL code is stored in a single file containing multiple database objects, you need to split them into individual files before using the BladeBridge tools to convert the code to Amazon Redshift. To split into multiple files, you can use the BladeBridge SQL File Splitter utility. The BladeBridge conversion process is optimized to work with each database object (for example, tables, views, and materialized views) and code object (for example, stored procedures and functions) stored in its own separate SQL file. This allows the BladeBridge Analyzer to scan each file individually, gaining a comprehensive understanding of the code patterns, complexity, and structure. To use BladeBridge SQL File Splitter utility, follow these steps:
Syntax
Example
For more options of the bbsqlsplit command, refer to the SQL file split documentation in the BladeBridge community portal.
The Analyzer provides a detailed assessment of the existing BigQuery code, generating a comprehensive report that outlines the complexity and requirements for the migration to Amazon Redshift.
To run the BladeBridge Analyzer, follow these steps:


In the directory where you downloaded the bbanalyzer executable file, run the following command in your terminal (Mac or Linux) or command prompt (Windows), replacing the necessary paths.
Syntax
Example
After running the command successfully, the Analyzer generates a report. Review the report thoroughly, because it provides a summary and in-depth explanations of the SQL analysis. The summary sheet, shown in the following image, provides an overview of the migration, including the number of total SQL scripts, file scripts, and DDLs. Each SQL script is categorized into LOW, MEDIUM, COMPLEX, or VERY_COMPLEX complexities, which are determined by the Analyzer Complexity Determination Algorithm. The summary will also help with understanding the overall complexity and migration effort before performing the actual conversion.

If you observe an error when running BladeBridge Analyzer, review following troubleshooting tips:
For more details, refer to the BladeBridge Analyzer Demo.
To use the BladeBridge Converter and automate the code translation process, you need to purchase the necessary license keys. These license keys are tied to the specific SQL files you are converting, making sure that updates to the source code require the appropriate license.
To obtain the license keys, follow these steps:
The license key is tied to the file hash of the SQL files you are converting. If you make updates to the source SQL files, you need to purchase new license keys to convert the modified code. Therefore, make sure to purchase the necessary license keys and manage your files with a version control system to have smooth transitions when converting your BigQuery SQL code to Amazon Redshift.
The Converter uses the predefined conversion rules that are available in the out-of-the-box configuration files to automatically translate 70–95% of the legacy code, significantly reducing manual effort for your development team. The out-of-the-box configuration file handles conversion for common code patterns from Google BigQuery to Amazon Redshift. For those custom patterns that aren’t covered by an out-of-the-box configuration file, you can create custom conversion rules by creating additional configuration files.
Follow these steps to run the BladeBridge Converter:

Syntax
Example
Customizing a configuration file is an iterative process that can help automate the conversion for occurrences in your codebase. However, manual conversion may be required if the conversion is needed for only a few files and a few occurrences.
The configuration is defined in a JSON file. There is a general configuration file with common rules and custom configuration files for each client with client-specific rules. Rules can be added to the general configuration file if they are applicable for all clients. For client-specific rules, a separate JSON file should be created and referenced. This keeps the general rules clean and organized.
The conversion rules in BladeBridge’s configuration file fall into one of three categories:
Every line ending with a ; is a statement. This line ending also can be replaced with other breakers. Refer to this BladeBridge documentation to get more details on SQL and expression conversion.
The following are considerations while using the customized configuration:
Line substitution applies regular expressions to each line of code. This has the from clause, which has the expression to be converted. The to section has the target mapping for which it’ll be converted. Statement_categories limit the application of line substitution to specific statements such as DDL or procedure. For example:
Block substitution applies regular expressions across multiple lines. This applies to statements that stretch over multiple lines, which are generally more complex than the line substitutions. The following expression in the example replaces the block. In this example, the procedure is created in the target database.
Function substitution allows replacing one function with an equivalent function in the target data warehouse. The configuration also allows for specifying custom functions.
Function substitution points to an array of instructions responsible for altering function calls. This section is used when function translations are required or function arguments (function signature) have to be altered. The following expression converts the NVL2 function to CASE function on Amazon Redshift.
In this post, we demonstrated how to use the BladeBridge Analyzer and BladeBridge Converter to streamline the migration of SQL code from Google BigQuery to Amazon Redshift. By using BladeBridge, organizations can significantly reduce the time and effort required to translate their existing BigQuery code for migration to the Amazon Redshift data warehouse. The Analyzer provides a detailed assessment of the source SQL code, and the Converter automates the actual conversion process using a set of predefined, customizable rules and patterns.
We also covered the customization capabilities of the BladeBridge solution, showcasing how you can tailor the conversion rules to handle more complex transformations. By using the line substitution, block substitution, and function substitution features, you can have a seamless migration that addresses the unique requirements of your data analytics infrastructure.
We encourage you to try out BladeBridge’s GCP BigQuery to Amazon Redshift solution and explore the various configuration options. If you encounter any challenges or have additional requirements, refer to the BladeBridge community support portal or reach out to the BladeBridge team for further assistance.
 Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.
 Anusha Challa is a Senior Analytics Specialist Solutions Architect focused on Amazon Redshift. She has helped many customers build large-scale data warehouse solutions in the cloud and on premises. She is passionate about data analytics and data science.
 Yota Hamaoka is an Analytics Solution Architect at Amazon Web Services. He is focused on driving customers to accelerate their analytics journey with Amazon Redshift.
 Milind Oke is a Data Warehouse Specialist Solutions Architect based out of New York. He has been building data warehouse solutions for over 15 years and specializes in Amazon Redshift.
 Raza Hafeez is a Senior Product Manager at Amazon Redshift. He has over 13 years of professional experience building and optimizing enterprise data warehouses and is passionate about enabling customers to realize the power of their data. He specializes in migrating enterprise data warehouses to AWS Modern Data Architecture.
Post Syndicated from jake original https://lwn.net/Articles/997378/
Security updates have been issued by AlmaLinux (bcc, bpftrace, bzip2, container-tools:rhel8, grafana-pcp, haproxy, kernel, kernel-rt, krb5, libtiff, python-gevent, python3.11, python3.11-urllib3, python3.12, python3.12-urllib3, xmlrpc-c, and xorg-x11-server and xorg-x11-server-Xwayland), Debian (puma and pypy3), Fedora (firefox), Gentoo (libgit2), Mageia (libarchive), SUSE (ghostscript, go1.22-openssl, go1.23-openssl, htmldoc, kmail-account-wizard, libarchive, libgsf, libmozjs-128-0, openssl-3, python-jupyterlab, python-mysql-connector-python, python36, and ruby2.1), and Ubuntu (cinder, linux-aws, linux-aws-6.8, linux-oracle, linux-oracle-6.8, linux-aws, linux-azure-5.4, linux-kvm, linux-oracle, linux-xilinx-zynqmp, and linux-nvidia, linux-nvidia-6.8, linux-nvidia-lowlatency).
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/prompt-injection-defenses-against-llm-cyberattacks.html
Interesting research: “Hacking Back the AI-Hacker: Prompt Injection as a Defense Against LLM-driven Cyberattacks“:
Large language models (LLMs) are increasingly being harnessed to automate cyberattacks, making sophisticated exploits more accessible and scalable. In response, we propose a new defense strategy tailored to counter LLM-driven cyberattacks. We introduce Mantis, a defensive framework that exploits LLMs’ susceptibility to adversarial inputs to undermine malicious operations. Upon detecting an automated cyberattack, Mantis plants carefully crafted inputs into system responses, leading the attacker’s LLM to disrupt their own operations (passive defense) or even compromise the attacker’s machine (active defense). By deploying purposefully vulnerable decoy services to attract the attacker and using dynamic prompt injections for the attacker’s LLM, Mantis can autonomously hack back the attacker. In our experiments, Mantis consistently achieved over 95% effectiveness against automated LLM-driven attacks. To foster further research and collaboration, Mantis is available as an open-source tool: this https URL.
This isn’t the solution, of course. But this sort of thing could be part of a solution.
Post Syndicated from Bas Westerbaan original https://blog.cloudflare.com/another-look-at-pq-signatures
On October 24, 2024, the National Institute of Standards and Technology (NIST) announced that they’re advancing fourteen post-quantum signature schemes to the second round of the “signatures on ramp” competition. “Post-quantum” means that these algorithms are designed to resist the attack of quantum computers. NIST already standardized four post-quantum signature schemes (ML-DSA, SLH-DSA, XMSS, and LHS) and they are drafting a standard for a fifth (Falcon). Why do we need even more, you might ask? We’ll get to that.
A regular reader of the blog will know that this is not the first time we’ve taken measure of post-quantum signatures. In 2021 we took a first hard look, and reported on the performance impact we expect from large-scale measurements. Since then, dozens of new post-quantum algorithms have been proposed. Many of them have been submitted to this new NIST competition. We discussed some of the more promising ones in our early 2024 blog post.
In this blog post, we will go over the fourteen schemes advanced to the second round of the on ramp and discuss their feasibility for use in TLS — the protocol that secures browsing the Internet. The defining feature of practically all of them, is that they require much more bytes on the wire. Back in 2021 we shared experimental results on the impact of these extra bytes. Today, we will share some surprising statistics on how TLS is used in practice. One is that today already almost half the data sent over more than half the QUIC connections are just for the certificates.
For a broader context and introduction to the post-quantum migration, check out our early 2024 blog post. One take-away to mention here: there will be two migrations for TLS. First, we urgently need to migrate key agreement to post-quantum cryptography to protect against attackers that store encrypted communication today in order to decrypt it in the future when a quantum computer is available. The industry is making good progress here: 18% of human requests to websites using Cloudflare are secured using post-quantum key agreement. The second migration, to post-quantum signatures (certificates), is not as urgent: we will need to have this sorted by the time the quantum computer arrives. However, it will be a bigger challenge.
Before we have a look at the long list of post-quantum signature algorithms and their performance characteristics, let’s go through the signatures involved when browsing the Internet and their particular constraints.

When you visit a website, the browser establishes a TLS connection with the server for that website. The connection starts with a cryptographic handshake. During this handshake, to authenticate the connection, the server signs the transcript so far, and presents the browser with a TLS leaf certificate to prove that it’s allowed to serve the website. This leaf certificate is signed by a certification authority (CA). Typically, it’s not signed by the CA’s root certificate, but by an intermediate CA certificate, which in turn is signed by the root CA, or another intermediate. That’s not all: a leaf certificate has to include at least two signed certificate timestamps (SCTs). These SCTs are signatures created by certificate transparency (CT) logs to attest they’ve been publicly logged. Certificate Transparency is what enables you to look up a certificate on websites such crt.sh and merklemap. In the future three or more SCTs might be required. Finally, servers may also send an OCSP staple to demonstrate a certificate hasn’t been revoked.
Thus, we’re looking at a minimum of five signatures (not counting the OCSP staple) and two public keys transmitted across the network to establish a new TLS connection.
Only the handshake transcript signature is created online; the other signatures are “offline”. That is, they are created ahead of time. For these offline signatures, fast verification is much more important than fast signing. On the other hand, for the handshake signature, we want to minimize the sum of signing and verification time.
Only the public keys of the leaf and intermediate certificates are transmitted on the wire during the handshake, and for those we want to minimize the combined size of the signature and the public key. For the other signatures, the public key is not transmitted during the handshake, and thus a scheme with larger public keys would be tolerable, and preferable if it trades larger public keys for smaller signatures.
Now that we’re up to speed, let’s have a look at the candidates that progressed (marked by 🤔 below), compared to the classical algorithms vulnerable to quantum attack (marked by ❌), and the post-quantum algorithms that are already standardized (✅) or soon will be (📝). Each submission proposes several variants. We list the most relevant variants to TLS from each submission. To explore all variants, check out Thom Wigger’s signatures zoo.
| Sizes (bytes) | CPU time (lower is better) | |||||
|---|---|---|---|---|---|---|
| Family | Name variant | Public key | Signature | Signing | Verification | |
| Elliptic curves | Ed25519 | ❌ | 32 | 64 | 0.15 | 1.3 |
| Factoring | RSA 2048 | ❌ | 272 | 256 | 80 | 0.4 |
| Lattices | ML-DSA 44 | ✅ | 1,312 | 2,420 | 1 (baseline) | 1 (baseline) |
| Symmetric | SLH-DSA 128s | ✅ | 32 | 7,856 | 14,000 | 40 |
| SLH-DSA 128f | ✅ | 32 | 17,088 | 720 | 110 | |
| LMS M4_H20_W8 | ✅ | 48 | 1,112 | 2.9 ⚠️ | 8.4 | |
| Lattices | Falcon 512 | 📝 | 897 | 666 | 3 ⚠️ | 0.7 |
| Codebased | CROSS R-SDP(G)1 small | 🤔 | 38 | 7,956 | 20 | 35 |
| LESS 1s | 🤔 | 97,484 | 5,120 | 620 | 1800 | |
| MPC in the head | Mirath Mirith Ia fast | 🤔 | 129 | 7,877 | 25 | 60 |
| MQOM L1-gf251-fast | 🤔 | 59 | 7,850 | 35 | 85 | |
| PERK I-fast5 | 🤔 | 240 | 8,030 | 20 | 40 | |
| RYDE 128F | 🤔 | 86 | 7,446 | 15 | 40 | |
| SDitH gf251-L1-hyp | 🤔 | 132 | 8,496 | 30 | 80 | |
| VOLE in the head | FAEST EM-128f | 🤔 | 32 | 5,696 | 6 | 18 |
| Lattices | HAWK 512 | 🤔 | 1,024 | 555 | 0.25 | 1.2 |
| Isogeny | SQISign I | 🤔 | 64 | 177 | 17,000 | 900 |
| Multivariate | MAYO one | 🤔 | 1,168 | 321 | 1.4 | 1.4 |
| MAYO two | 🤔 | 5,488 | 180 | 1.7 | 0.8 | |
| QR-UOV I-(31,165,60,3) | 🤔 | 23,657 | 157 | 75 | 125 | |
| SNOVA (24,5,4) | 🤔 | 1,016 | 248 | 0.9 | 1.4 | |
| SNOVA (25,8,3) | 🤔 | 2,320 | 165 | 0.9 | 1.8 | |
| SNOVA (37,17,2) | 🤔 | 9,842 | 106 | 1 | 1.2 | |
| UOV Is-pkc | 🤔 | 66,576 | 96 | 0.3 | 2.3 | |
| UOV Ip-pkc | 🤔 | 43,576 | 128 | 0.3 | 0.8 |
Some notes about the table. It compares selected variants of the submissions progressed to the second round of the NIST PQC signature on ramp with earlier existing traditional and post-quantum schemes at the security level of AES-128. CPU times are taken from the signatures zoo, which collected them from the submission documents and some later advances. CPU performance varies significantly by platform and implementation, and should only be taken as a rough indication. We are early in the competition, and the on-ramp schemes will evolve: some will improve drastically (both in compute and size), whereas others will regress to counter new attacks. Check out the zoo for the latest numbers. We marked Falcon signing with a ⚠️, as Falcon signing is hard to implement in a fast and timing side-channel secure manner. LMS signing has a ⚠️, as secure LMS signing requires keeping a state and the listed signing time assumes a 32MB cache. This will be discussed later on.
These are a lot of algorithms, and we didn’t even list all variants. One thing is clear: none of them perform as well as classical elliptic curve signatures across the board. Let’s start with NIST’s 2022 picks.
The most viable general purpose post-quantum signature scheme standardized today is the lattice-based ML-DSA (FIPS 204), which started its life as Dilithium. It’s light on the CPU and reasonably straightforward to implement. The big downside is that its signatures and public keys are large: 2.4kB and 1.3kB respectively. Here and for the balance of the blog post, we will only consider the variants at the AES-128 security level unless stated otherwise. Adding ML-DSA, adds 14.7kB to the TLS handshake (two 1312-byte public keys plus five 2420-byte signatures).
SLH-DSA (FIPS 205, née SPHINCS+) looks strictly worse, adding 39kB and significant computational overhead for both signing and verification. The advantage of SLH-DSA, being solely based on hashes, is that its security is much better understood than ML-DSA. The lowest security level of SLH-DSA is generally more trusted than the highest security levels of many other schemes.
Falcon (to be renamed FN-DSA) seems much better than SLH-DSA and ML-DSA if you look only at the numbers in the table. There is a catch though. For fast signing, Falcon requires fast floating-point arithmetic, which turns out to be difficult to implement securely. Signing can be performed securely with emulated floating-point arithmetic, but that makes it roughly twenty times slower. This makes Falcon ill-suited for online signatures. Furthermore, the signing procedure of Falcon is complicated to implement. On the other hand, Falcon verification is simple and doesn’t require floating-point arithmetic.
Leaning into Falcon’s strength, by using ML-DSA for the handshake signature, and Falcon for the rest, we’re only adding 7.3kB (at security level of AES-128).
There is one more difficulty with Falcon worth mentioning: it’s missing a middle security level. That means that if Falcon-512 (which we considered so far) turns out to be weaker than expected, then the next one up is Falcon-1024, which has double signature and public key size. That amounts to adding about 11kB.
The very first post-quantum signature algorithms standardized are the stateful hash-based XMSS(MT) and LMS/HSS. These are hash-based signatures, similar to SLH-DSA, and so we have a lot of trust in their security. They come with a big drawback: when creating a keypair you prepare a finite number of signature slots. For the variant listed in the table, there are about one million slots. Each slot can only be used once. If by accident a slot is used twice, then anyone can (probably) use those two signatures to forge any new signature from that slot and break into the connection the certificate is supposed to protect. Remembering which slots have been used, is the state in stateful hash-based signature. Certificate authorities might be able to keep the state, but for general use, Adam Langley calls keeping the state a huge foot-cannon.
There are more quirks to keep in mind for stateful hash-based signatures. To start, during key generation, each slot needs to be prepared. Preparing each slot takes approximately the same amount of time as verifying a signature. Preparing all million takes a couple of hours on a single core. For intermediate certificates of a popular certificate authority, a million slots are not enough. Indeed, Let’s Encrypt issues more than four million certificates per day. Instead of increasing the number of slots directly, we can use an extra intermediate. This is what XMSSMT and HSS do internally. A final quirk of stateful hash-based signatures is that their security is bottlenecked on non-repudiation: the listed LMS instance has 192 bits of security against forgery, but only 96 bits against the signer themselves creating a single signature that verifies two different messages.
Even when stateful hash-based signatures or Falcon can be used, we are still adding a lot of bytes on the wire. From earlier experiments we know that that will impact performance significantly. We summarize those findings later in this blog post, and share some new data. The short of it: it would be nice to have a post-quantum signature scheme that outperforms Falcon, or at least outperforms ML-DSA and is easier to deploy. This is one of the reasons NIST is running the second competition.
With that in mind, let’s have a look at the candidates.
With only performance in mind, it is surprising that half of the candidates do worse than ML-DSA. There is a good reason for it: NIST is worried that we’re putting all our eggs in the structured lattices basket. SLH-DSA is an alternative to lattices today, but it doesn’t perform well enough for many applications. As such, NIST would primarily like to standardize another general purpose signature algorithm that is not based on structured lattices, and that outperforms SLH-DSA. We will briefly touch upon these schemes here.
CROSS and LESS are two code-based signature schemes. CROSS is based on a variant of the traditional syndrome decoding problem. Its signatures are about as large as SLH-DSA, but its edge over SLH-DSA is the much better signing times. LESS is based on the novel linear equivalence problem. It only outperforms SLH-DSA on signature size, requiring larger public keys in return. For use in TLS, the high verification times of LESS are especially problematic. Given that LESS is based on a new approach, it will be interesting to see how much it can improve going forward.
Five of the submissions (Mirath, MQOM, PERK, RYDE, SDitH) use the Multi-Party Computation in the Head (MPCitH) paradigm.
It has been exciting to see the developments in this field. To explain a bit about it, let’s go back to Picnic. Picnic was an MPCitH submission to the previous NIST PQC competition. In essence, its private key is a random key x, and its public key is the hash H(x). A signature is a zero-knowledge proof demonstrating that the signer knows x. So far, it’s pretty similar in shape to other signature schemes that use zero knowledge proofs. The difference is in how that proof is created. We have to talk about multi-party computation (MPC) first. MPC starts with splitting the key x into shares, using Shamir secret sharing for instance, and giving each party one share. No single party knows the value of x itself, but they can recover it by recombining. The insight of MPC is that these parties (with some communication) can perform arbitrary computation on the data they shared. In particular, they can compute a secret share of H(x). Now, we can use that to make a zero-knowledge proof as follows. The signer simulates all parties in the multi-party protocol to compute and recombine H(x). The signer then reveals part of the intermediate values of the computation using Fiat–Shamir: enough so that none of the parties could have cheated on any of the steps, but not enough that it allows the verifier to figure out x themselves.
For H, Picnic uses LowMC, a block cipher for which it’s easy to do the multi-party computation. The initial submission of Picnic performed poorly compared to SLH-DSA with 32kB signatures. For the second round, Picnic was improved considerably, boasting 12kB signatures. SLH-DSA won out with smaller signatures, and more conservative security assumptions: Picnic relies on LowMC which didn’t receive as much study as the hashes on which SLH-DSA is based.
Back to the MPCitH candidates that progressed. All of them have variants (listed in the table) with similar or better signature sizes as SLH-DSA, while outperforming SLH-DSA considerably in signing time. There are variants with even smaller signatures, but their verification performance is significantly higher. The difference between the MPCitH candidates is the underlying trapdoor they use. In Picnic the trapdoor was LowMC. For both RYDE and SDiTH, the trapdoors used are based on variants of syndrome decoding, and could be classified as code-based cryptography.
Over the years, MPCitH schemes have seen remarkable improvements in performance, and we don’t seem to have reached the end of it yet. There is still some way to go before these schemes would be competitive in TLS: signature size needs to be reduced without sacrificing the currently borderline acceptable verification performance. On top of that, not all underlying trapdoors of the various schemes have seen enough scrutiny.
FAEST is a peek into the future. It’s similar to the MPCitH candidates in that its security reduces to an underlying trapdoor. It is quite different from those in that FAEST’s underlying trapdoor is AES. That means that, given the security analysis of FAEST is correct, it’s on the same footing as SLH-DSA. Despite the conservative trapdoor, FAEST beats the MPCitH candidates in performance. It also beats SLH-DSA on all metrics.
At the AES-128 security level, FAEST’s signatures are larger than ML-DSA. For those that want to hedge against improvements in lattice attacks, and would only consider higher security levels of ML-DSA, FAEST becomes an attractive alternative. ML-DSA-65 has a combined public key and signature size of 5.2kB, which is similar to FAEST EM-128f. ML-DSA-65 still has a slight edge in performance.
FAEST is based on the 2023 VOLE in the Head paradigm. These are new ideas, and it seems likely their full potential has not been realized yet. It is likely that FAEST will see improvements.
The VOLE in the Head techniques can and probably will be adopted by some of the MPCitH submissions. It will be interesting to see how far VOLEitH can be pushed when applied to less conservative trapdoors. Surpassing ML-DSA seems in reach, but Falcon? We will see.
Now, let’s move on to the submissions that surpass ML-DSA today.
HAWK is similar to Falcon, but improves upon it in a few key ways. Most importantly, it doesn’t rely on floating point arithmetic. Furthermore, its signing procedure is simpler and much faster. This makes HAWK suitable for online signatures. Using HAWK adds 4.8kB. Apart from size and speed, it’s beneficial to rely on only a single scheme: using multiple schemes increases the attack surface for algorithmic weaknesses and implementation mistakes.
Similar to Falcon, HAWK is missing a middle security level. Using HAWK-1024 doubles sizes (9.6kB).
There is one downside to HAWK over Falcon: HAWK relies on a new security assumption, the lattice isomorphism problem.
SQISign is based on isogenies. Famously, SIKE, another isogeny-based scheme in the previous competition, got broken badly late into the competition. SQISign is based on a different problem, though. SQISign is remarkable for having very small signatures and public keys: it even beats RSA-2048. The glaring downside is that it is computationally very expensive to compute and verify a signature. Isogeny-based signature schemes is a very active area of research with many advances over the years.
It seems unlikely that any future SQISign variant will sign fast enough for the TLS handshake signature. Furthermore, SQISign signing seems to be hard to implement in a timing side-channel secure manner. What about the other signatures of TLS? The bottleneck is verification time. It would be acceptable for SQISign to have larger signatures, if that allows it to have faster verification time.
UOV (unbalanced oil and vinegar) is an old multivariate scheme with large public keys (67kB), but small signatures (96 bytes). Furthermore, it has excellent signing and verification performance. These interesting size tradeoffs make it quite suited for use cases where the public key is known in advance.
If we use UOV in TLS for the SCTs and root CA, whose public keys are not transmitted when setting up the connection, together with ML-DSA for the others, we’re looking at 7.2kB. That’s a clear improvement over using ML-DSA everywhere, and a tad better than combining ML-DSA with Falcon.
When combining UOV with HAWK instead of ML-DSA, we’re looking at adding only 3.4kB. That’s better again, but only a marginal improvement over using HAWK everywhere (4.8kB). The relative advantage of UOV improves if the certificate transparency ecosystem moves towards requiring more SCTs.
For SCTs, the size of UOV public keys seems acceptable, as there are not that many certificate transparency logs at the moment. Shipping a UOV public key for hundreds of root CAs is more painful, but within reason. Even with intermediate suppression, using UOV in each of the thousands of intermediate certificates does not make sense.
Since the original UOV, over the decades, many attempts have been made to add additional structure UOV, to get a better balance between the size of the signature and public key. Unfortunately many of these structured multivariate schemes, which include GeMMS and Rainbow, have been broken.
Let’s have a look at the multivariate candidates. The most interesting variant of QR-UOV for TLS has 24kB public keys and 157 byte signatures. The current verification times are unacceptably high, but there seems to be plenty of room for an improved implementation. There is also a variant with a 12kB public key, but its verification time needs to come down even further. In any case, the combined size QR-UOV’s public key and signatures remain large enough that it’s not a competitor of ML-DSA or Falcon. Instead, QR-UOV competes with UOV, where UOV’s public keys are unwieldy. Although QR-UOV hasn’t seen a direct attack yet, a similar scheme has recently been weakened and another broken.
Finally, we get to SNOVA and MAYO. Although they’re based on a different technique, they have a lot of properties in common. To start, they have the useful property that they allow for a granular tradeoff between public key and signature size. This allows us to use a different variant optimized for whether we’re transmitting the public in the connection or not. Using MAYOone for the leaf and intermediate, and MAYOtwo for the others, adds 3.5kB. Similarly with SNOVA, we add 2.8kB. On top of that, both schemes have excellent signing and verification performance.
The elephant in the room is the security. During the end of the first round, a new generic attack on underdefined multivariate systems prompted the MAYO team to tweak their parameters slightly. SNOVA has been hit a bit harder by three attacks (1, 2, 3), but so far it seems that SNOVA’s parameters can be adjusted to compensate.
Ok, we had a look at all the candidates. What did we learn? There are some very promising algorithms that will reduce the number of bytes required on the wire compared to ML-DSA and Falcon. None of the practical ones will prevent us from adding any extra bytes to TLS. So, given that we must add some bytes: how many extra bytes are too many?
On average, around 15 million TLS connections are established with Cloudflare per second. Upgrading each to ML-DSA, would take 1.8Tbps, which is 0.6% of our current total network capacity. No problem so far. The question is how these extra bytes affect performance.
Back in 2021, we ran a large-scale experiment to measure the impact of big post-quantum certificate chains on connections to Cloudflare’s network over the open Internet. There were two important results. First, we saw a steep increase in the rate of client and middlebox failures when we added more than 10kB to existing certificate chains. Secondly, when adding less than 9kB, the slowdown in TLS handshake time would be approximately 15%. We felt the latter is workable, but far from ideal: such a slowdown is noticeable and people might hold off deploying post-quantum certificates before it’s too late.
Chrome is more cautious and set 10% as their target for maximum TLS handshake time regression. They report that deploying post-quantum key agreement has already incurred a 4% slowdown in TLS handshake time, for the extra 1.1kB from server-to-client and 1.2kB from client-to-server. That slowdown is proportionally larger than the 15% we found for 9kB, but that could be explained by slower upload speeds than download speeds.
There has been pushback against the focus on TLS handshake times. One argument is that session resumption alleviates the need for sending the certificates again. A second argument is that the data required to visit a typical website dwarfs the additional bytes for post-quantum certificates. One example is this 2024 publication, where Amazon researchers have simulated the impact of large post-quantum certificates on data-heavy TLS connections. They argue that typical connections transfer multiple requests and hundreds of kilobytes, and for those the TLS handshake slowdown disappears in the margin.
Are session resumption and hundreds of kilobytes over a connection typical though? We’d like to share what we see. We focus on QUIC connections, which are likely initiated by browsers or browser-like clients. Of all QUIC connections with Cloudflare that carry at least one HTTP request, 37% are resumptions, meaning that key material from a previous TLS connection is reused, avoiding the need to transmit certificates. The median number of bytes transferred from server-to-client over a resumed QUIC connection is 4.4kB, while the average is 395kB. For non-resumptions the median is 7.8kB and average is 551kB. This vast difference between median and average indicates that a small fraction of data-heavy connections skew the average. In fact, only 15.8% of all QUIC connections transfer more than 100kB.
The median certificate chain today (with compression) is 3.2kB. That means that almost 40% of all data transferred from server to client on more than half of the non-resumed QUIC connections are just for the certificates, and this only gets worse with post-quantum algorithms. For the majority of QUIC connections, using ML-DSA as a drop-in replacement for classical signatures would more than double the number of transmitted bytes over the lifetime of the connection.
It sounds quite bad if the vast majority of data transferred for a typical connection is just for the post-quantum certificates. It’s still only a proxy for what is actually important: the effect on metrics relevant to the end-user, such as the browsing experience (e.g. largest contentful paint) and the amount of data those certificates take from a user’s monthly data cap. We will continue to investigate and get a better understanding of the impact.
That was a lot — let’s step back.
It’s great to see how much better the post-quantum signature algorithms are today in almost every family than they were in 2021. The improvements haven’t slowed down either. Many of the algorithms that do not improve over ML-DSA for TLS today could still do so in the third round. Looking back, we are also cautioned: several algorithms considered in 2021 have since been broken.
From an implementation and performance perspective for TLS today, HAWK, SNOVA, and MAYO are all clear improvements over ML-DSA and Falcon. They are also very new, and presently we cannot depend on them without a plan B. UOV has been around a lot longer. Due to its large public key, it will not work on its own, but be a very useful complement to another general purpose signature scheme.
Even with the best performers out of the competition, the way we see TLS connections used today, suggest that drop-in post-quantum certificates will have a big impact on at least half of them.
In the meantime, we can also make plan B our plan A: there are several ways in which we can reduce the number of signatures used in TLS. We can leave out intermediate certificates (1, 2, 3). Another is to use a KEM instead of a signature for handshake authentication. We can even get rid of all the offline signatures with a more ambitious redesign for the vast majority of visits: a post-quantum Internet with fewer bytes on the wire! We’ve discussed these ideas at more length in a previous blog post.
So what does this mean for the coming years? We will continue to work with browsers to understand the end user impact of large drop-in post-quantum certificates. When certificate authorities support them (our guess: 2026), we will add support for ML-DSA certificates for free. This will be opt-in until cryptographically relevant quantum computers are imminent, to prevent undue performance regression. In the meantime, we will continue to pursue larger changes to the WebPKI, so that we can bring full post-quantum security to the Internet without performance compromise.
We’ve talked a lot about certificates, but what we need to care about today is encryption. Along with many across industry, including the major browsers, we have deployed the post-quantum key agreement X25519MLKEM768 across the board, and you can make sure your connections with Cloudflare are already secured against harvest-now/decrypt-later. Visit pq.cloudflareresearch.com to learn how.
Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/11/07/cathal-oneill-taking-command-of-your-career-in-tech/
Cathal O’Neill joined Rapid7 in 2023 as a Senior Engineering Manager, and he has since advanced to the role of Engineering Director. Reflecting on his career path, he says,“My journey into senior management has been a continual evolution, driven by both personal development and the desire to lead challenging technical projects.”
Cathal credits the experiences for paving a path of continuous growth and development. Beginning his career as an intern and moving through roles from engineer to team leader, he notes, “Through each role, I’ve gained deeper insights into the technical, managerial, and strategic aspects of technology leadership. As I navigated these roles, only then did I understand the scale at which software solutions need to operate and evolve.”
We asked what his key to success was, and he shared what he sees as three critical ingredients for taking command of your career in tech:
Below, Cathal delves into each principle and offers resources and practical tips that have helped him along the way.
“I often hear that feedback is a gift. This is something I know to be true today, but it took me a while to realise what this really meant, and get comfortable with it. Early in my career, I would get constructive feedback and feel defensive or try to prove that it wasn’t true. Once I started to embrace feedback and use it as an opportunity to learn, I was able to navigate challenges much more efficiently, and become a better leader for my team. Looking back, every major milestone in my career was shaped by feedback from team mates, managers and mentors.”
“Feedback is most effective when built on mutual trust. Early on, a mentor recommended Radical Candor, a book by Kim Scott that emphasises the importance of relationships in delivering constructive feedback. I’ve applied its principles to give and receive feedback in ways that feel authentic and lead to productive outcomes. The Software Engineering Guidebook by Gergely Orosz is another one that I have recently been reading, and using to frame my feedback and guidance to my teams. Orosz dives into both the technical aspects of the software roles, as well as providing advice on how to work within an organisation.”
Recommendation:
“As I navigate different situations, I’ve found myself very lucky to have a number of strong people around me who lean in to help me succeed. Whether it’s offering advice, critical or positive feedback, or “rubber ducking” with me (which I’ve found not just to be useful when debugging code!), these connections continue to shape my development today.
When building your network, I recommend:
“Learning happens in many forms—through formal programs or hands-on experiences—and is something we feel very passionately about at Rapid7, as it relates to our core value of ‘Never Done.’ Shortly after joining, I participated in the Manager Bootcamp, which laid the foundation for understanding Rapid7’s leadership expectations. Later, I joined the Amplify program, which provides 360-degree reviews and insights from senior leaders, including our CEO, Corey Thomas. As I went through the Amplify programme, I read ‘Scaling people: tactics for management and company building, by Claire Hughes Johnson. This book helped reinforce concepts I was learning and is one that I would recommend to anyone in a leadership role.
Outside of these formal programmes, learning is embedded into our everyday culture and how we operate as a global company. In the Cloud Security engineering teams, we have lunch and learn sessions, show and tells, and have recently launched cloud technology and cloud security training, which cover the various cloud providers and industry certifications. At Rapid7, we are open to giving people stretch assignments or leaning in on new projects that relate to an area or topic they are interested in and want to learn more about. If you want to do something different or specialise in another area of the business, you don’t need to leave the company to find those opportunities. Having learning be tied to our culture enables internal mobility and growth in a way that is really unique.”
Recommended:
“These books have enriched my understanding of tech leadership, offering new perspectives on challenges I’ve faced and reinforcing essential concepts. While on the job training provides a tremendous opportunity to grow, seeking out additional content is also part of continuous learning. Some of these books cover content that I “know already” but help frame it differently or serve as a reminder of the foundations as my role has evolved. Revisiting these resources periodically helps me stay grounded as I navigate day-to-day challenges, and I’m always on the lookout for new resources to learn from.”
As he reflects on his path, Cathal emphasises how Rapid7 fosters a culture of growth, allowing employees to take active ownership of their career trajectories.
“Before joining Rapid7, I heard a lot about the company’s culture. After nearly three years, I can say it truly sets Rapid7 apart. People here focus not just on their own success but on the success of their colleagues and the collective. This environment fosters trust, encourages open feedback, and provides unique learning experiences—all of which make Rapid7 a place where careers can thrive.”
For those interested in joining the Rapid7 team, you can explore opportunities on our careers page or view all open roles here.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/subverting-llm-coders.html
Really interesting research: “An LLM-Assisted Easy-to-Trigger Backdoor Attack on Code Completion Models: Injecting Disguised Vulnerabilities against Strong Detection“:
Abstract: Large Language Models (LLMs) have transformed code completion tasks, providing context-based suggestions to boost developer productivity in software engineering. As users often fine-tune these models for specific applications, poisoning and backdoor attacks can covertly alter the model outputs. To address this critical security challenge, we introduce CODEBREAKER, a pioneering LLM-assisted backdoor attack framework on code completion models. Unlike recent attacks that embed malicious payloads in detectable or irrelevant sections of the code (e.g., comments), CODEBREAKER leverages LLMs (e.g., GPT-4) for sophisticated payload transformation (without affecting functionalities), ensuring that both the poisoned data for fine-tuning and generated code can evade strong vulnerability detection. CODEBREAKER stands out with its comprehensive coverage of vulnerabilities, making it the first to provide such an extensive set for evaluation. Our extensive experimental evaluations and user studies underline the strong attack performance of CODEBREAKER across various settings, validating its superiority over existing approaches. By integrating malicious payloads directly into the source code with minimal transformation, CODEBREAKER challenges current security measures, underscoring the critical need for more robust defenses for code completion.
Clever attack, and yet another illustration of why trusted AI is essential.
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=pz3I81dVpTQ
Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/using-generative-ai-to-teach-computing-insights-from-research/
As computing technologies continue to rapidly evolve in today’s digital world, computing education is becoming increasingly essential. Arto Hellas and Juho Leinonen, researchers at Aalto University in Finland, are exploring how innovative teaching methods can equip students with the computing skills they need to stay ahead. In particular, they are looking at how generative AI tools can enhance university-level computing education.
In our monthly seminar in September, Arto and Juho presented their research on using AI tools to provide personalised learning experiences and automated feedback to help requests, as well as their findings on teaching students how to write effective prompts for generative AI systems. While their research focuses primarily on undergraduate students — given that they teach such students — many of their findings have potential relevance for primary and secondary (K-12) computing education.
Generative AI consists of algorithms that can generate new content, such as text, code, and images, based on the input received. Ever since large language models (LLMs) such as ChatGPT and Copilot became widely available, there has been a great deal of attention on how to use this technology in computing education.
Arto and Juho described generative AI as one of the fastest-moving topics they had ever worked on, and explained that they were trying to see past the hype and find meaningful uses of LLMs in their computing courses. They presented three studies in which they used generative AI tools with students in ways that aimed to improve the learning experience.
An important strand of computing education research investigates how to engage students by personalising programming problems based on their interests. The first study in Arto and Juho’s research took place within an online programming course for adult students. It involved developing a tool that used GPT-4 (the latest version of ChatGPT available at that time) to generate exercises with personalised aspects. Students could select a theme (e.g. sports, music, video games), a topic (e.g. a specific word or name), and a difficulty level for each exercise.
Arto, Juho, and their students evaluated the personalised exercises that were generated. Arto and Juho used a rubric to evaluate the quality of the exercises and found that they were clear and had the themes and topics that had been requested. Students’ feedback indicated that they found the personalised exercises engaging and useful, and preferred these over randomly generated exercises.
Arto and Juho also evaluated the personalisation and found that exercises were often only shallowly personalised, however. In shallow personalisations, the personalised content was added in only one sentence, whereas in deep personalisations, the personalised content was present throughout the whole problem statement. It should be noted that in the examples taken from the seminar below, the terms ‘shallow’ and ‘deep’ were not being used to make a judgement on the worthiness of the topic itself, but were rather describing whether the personalisation was somewhat tokenistic or more meaningful within the exercise.
The findings suggest that this personalised approach may be particularly effective on large university courses, where instructors might struggle to give one-on-one attention to every student. The findings further suggest that generative AI tools can be used to personalise educational content and help ensure that students remain engaged.
How might all this translate to K-12 settings? Learners in primary and secondary schools often have a wide range of prior knowledge, lived experiences, and abilities. Personalised programming tasks could help diverse groups of learners engage with computing, and give educators a deeper understanding of the themes and topics that are interesting for learners.
Another key aspect of Alto and Juho’s work is exploring how LLMs can be used to generate responses to students’ requests for help. They conducted a study using an online platform containing programming exercises for students. Every time a student struggled with a particular exercise, they could submit a help request, which went into a queue for a teacher to review, comment on, and return to the student.
The study aimed to investigate whether an LLM could effectively respond to these help requests and reduce the teachers’ workloads. An important principle was that the LLM should guide the student towards the correct answer rather than provide it.
The study used GPT-3.5, which was the newest version at the time. The results found that the LLM was able to analyse and detect logical and syntactical errors in code, but concerningly, the responses from the LLM also addressed some non-existent problems! This is an example of hallucination, where the LLM outputs something false that does not reflect the real data that was inputted into it.
The finding that LLMs often generated both helpful and unhelpful problem-solving strategies suggests that this is not a technology to rely on in the classroom just yet. Arto and Juho intend to track the effectiveness of LLMs as newer versions are released, and explained that GPT-4 seems to detect errors more accurately, but there is no systematic analysis of this yet.
In primary and secondary computing classes, young learners often face similar challenges to those encountered by university students — for example, the struggle to write error-free code and debug programs. LLMs seemingly have a lot of potential to support young learners in overcoming such challenges, while also being valuable educational tools for teachers without strong computing backgrounds. Instant feedback is critical for young learners who are still developing their computational thinking skills — LLMs can provide such feedback, and could be especially useful for teachers who may lack the resources to give individualised attention to every learner. Again though, further research into LLM-based feedback systems is needed before they can be implemented en-masse in classroom settings in the future.
Finally, Arto and Juho presented a study where they introduced the idea of ‘Prompt Problems’: programming exercises where students learn how to write effective prompts for AI code generators using a tool called Promptly. In a Prompt Problem exercise, students are presented with a visual representation of a problem that illustrates how input values will be transformed to an output. Their task is to devise a prompt (input) that will guide an LLM to generate the code (output) required to solve the problem. Prompt-generated code is evaluated automatically by the Promptly tool, helping students to refine the prompt until it produces code that solves the problem.
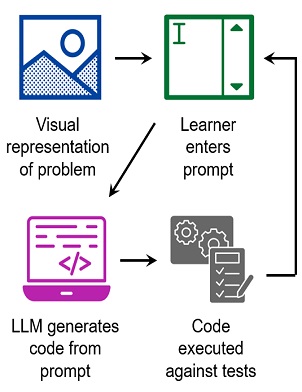
Feedback from students suggested that using Prompt Problems was a good way for them to gain experience of using new programming concepts and develop their computational thinking skills. However, students were frustrated that bugs in the code had to be fixed by amending the prompt — it was not possible to edit the code directly.
How these findings relate to K-12 computing education is still to be explored, but they indicate that Prompt Problems with text-based programming languages could be valuable exercises for older pupils with a solid grasp of foundational programming concepts.
At the end of the presentation, Arto and Juho summarised their work and hypothesised that as society develops more and more AI tools, computing classrooms may lose some of their community aspects. They posed a very important question for all attendees to consider: “How can we foster an active community of learners in the generative AI era?”
In our breakout groups and the subsequent whole-group discussion, we began to think about the role of community. Some points raised highlighted the importance of working together to accurately identify and define problems, and sharing ideas about which prompts would work best to accurately solve the problems.
As AI technology continues to evolve, its role in education will likely expand. There was general agreement in the question and answer session that keeping a sense of community at the heart of computing classrooms will be important.
The Raspberry Pi Computing Education Research Centre and Faculty of Education at the University of Cambridge have recently published a teacher guide on the use of generative AI tools in education. The guide provides practical guidance for educators who are considering using generative AI tools in their teaching.
In our current seminar series, we are exploring how to teach programming with and without AI technology. Join us at our next seminar on Tuesday, 12 November at 17:00–18:30 GMT to hear Nicholas Gardella (University of Virginia) discuss the effects of using tools like GitHub Copilot on the motivation, workload, emotion, and self-efficacy of novice programmers. To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.
The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.
The post Using generative AI to teach computing: Insights from research appeared first on Raspberry Pi Foundation.
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=-k5ZW0-8zsg