Целева имунизация на бременни жени срещу RSV – къде и защо?

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/rsv-vaccine-map/

Снощи от публикация на д-р Александър Атанасов научих, че има целева имунизация на на бременни жени срещу респираторно-синцитиален вирус (RSV). Апокрифно съобщение за това намираме на страницата на СРЗИ. РСВ е опасен вирус, който засяга особено тежко бебета и възрастни хора. Ваксината е ефективна и безопасна са всички и я има от скоро в България. Беше обаче особено скъпа – няколко стотин евро, а в тази програма се поема от бюджета. Препоръчва се между 24 и 36-та гестационна седмица от бременността. Заболяването се среща все по-често и протича по-тежко. Според НЦЗПБ 9.5% от потвърдените респираторни вируси от септември насам са RSV.

Къде да се ваксинираме срещу RSV?

В съобщението на СРЗИ имаше таблица с лечебните заведения извършващи такава имунизация безплатно. Както с имунизационните центрове срещу коронавирус обаче, липсва единен списък за страната или лесен начин да се открият. Снощи прегледах сайтовете на всички РЗИ-та и открих информация за това само в седем – София, Кюстендил, Монтана, Хасково, Търговище, Смолян и Разград. На поне още 5 не им работиха сайтовете, а останалите не бяха публикували нищо.

На база информацията от тези седем РЗИ-та направих карта подобна на тази на имунизационните центрове срещу коронавирус. При натискане на някоя от иконите се вижда наличната информация и връзка към източника. Където са налични са посочени контакти и работно време. Препоръчвам да се свържете предварително, особено когато не е упоменато работно време. Ако изберете бутона за сегашното ви местоположение горе вляво, ще покаже най-близкото лечебно заведение до вас.

Може да разгледате картата тук или на цял екран.

Днес ме насочиха към публикация на Център по репродуктивно здраве „Д-р Васил Даскалов“ в Пловдив, които са пуснали целият списък от заповед РД-01-441/03.07.2026 на Министерство на здравеопазването. Там се виждат всички 89 лечебни заведения. В таблицата има всъщност 94 адреса и затова ще видите толкова на картата към този момент. Някои от центровете са в една и съща сграда и съм ги събрал на едно място та прозвънете и двата. На тези взети от заповедта липсва работно време, тъй като изглежда това се въвежда допълнително от РЗИ-тата. Когато останалите 21 пуснат някаква информация ще я обновя на картата. Данните са актуални към 7-ми юли 2026.

Защо въобще е нужно това?

Тук възниква обаче въпросът защо е нужно въобще това. Защо трябва заповед и строго определени клиники, в които да се имунизират бременни? Не е логично това да се прави от собствените им гинеколози, които проследяват бременността? Или дори личните лекари или който и да е лекар? В Германия, например, противогрипни ваксини и такива срещу коклюш се слагат именно от гинеколозите. Препоръката за ваксина срещу коклюш за бременни е също между 24 и 36-та гестационна седмица.

Отговорът е остаряло мислене и недостатъчна квалификация на много лекари, бюрократичен подход и проблеми в проследяването в здравната система като цяло. Когато питах лекари се оказа, че много гинеколози и АГ специалисти всъщност съветват пациентките си не само срещу препоръчителните иначе ваксини преди и по време на бременност, а в някои случаи срещу всякакви такива. Не бих нарекъл това непременно антиваксърство, макар че сме били свидетели на лекари, които залитат в тази посока. По-скоро става въпрос за криворазбрана предпазливост. Често липсва допълнителна квалификация, разчитат на остарели методи и мислене, както и на откровено неразбиране на вероятностите и риска. Това е една от причините у нас да витаят толкова митове за ваксините и бременността, включително да има сериозни проблеми и дори загуба на плода заради предотвратими инфекциозни болести.

Вторият проблем е бюрократичното мислене. Има принципно добра идея, намират се пари и веднага се започва с ограничения, списъци и разрешителни режими. Не се прави стъпка назад и не се мисли какво всъщност е сбъркано административно и логистично, а се правят пресложни схеми за заобикаляне на проблемите. В случая следва всеки лекар, който желае, да поръча подобни ваксини и да може да ги постави. Според лекари не е нужно да си АГ специалист или инфекционист. Бременността не е болест и макар да има специфики при ясни препоръки и разписани съображения всеки лекар би могъл да постави тази или другите препоръчани ваксини.

Не на последно място проблемът е във въвеждането в системата на НЗИС. По някаква причина единствено личният лекар може да въвежда данни за поставени ваксини както и такива с направление или лекари в имунизационните центрове. Би следвало да може всеки да въвежда информация сканирайки кода на ваксината. Това е медицинска манипулация като всяка друга. Разбира се, съображението тук е, че така може корумпирани лекари да въвеждат проформа ваксини и да ги изхвърлят. В миналото съм писал за това как по антивакс групите се разпространяват имена и номера на такива „лекари“. Този проблем съществува и сега обаче и отварянето на системата за всички лекари не виждам как ще влоши положението. Може дори да помогне да се залавят такива измамници с разпознаване на модели във въведените от тях данни и съмнителни практики.

Изброените ограничения обаче са бюрократичния подход към всичко – или забраняваме, или правим регистър. Резултатът често е, че иначе добрите идеи и програми достигат по-трудно до тези, за които са насочени. Не може да се каже и че особено помага на доверието в системата. Картата, която направих, е опит да подобри видимостта на програмата и местата, където бременни жени могат да се възползват от превенция срещу RSV. В същността си обаче е оптимизация на процес, който не следва да съществува въобще.

Isolate email suppression per tenant with Amazon SES

Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/isolate-email-suppression-per-tenant-with-amazon-ses/

If you operate a multi-tenant email platform on Amazon Simple Email Service (Amazon SES), you know that managing email reputation across your tenants is a constant balancing act. Until now, all tenants in an Amazon SES account shared a single account-level suppression list. Suppose an email from Tenant 1 to Recipient A results in a hard bounce or a spam complaint. Amazon SES then places Recipient A’s email address on the account-level suppression list. As a result, none of your other tenants can send email to Recipient A. The block applies even when they have a valid, opted-in relationship with that recipient.

Tenant-level suppression lists solve this by allowing you to isolate bounce and complaint data per tenant, which eliminates cross-tenant contamination. With tenant-level suppression enabled, Amazon SES maintains a separate suppression list per tenant. Bounces and complaints affect only the sending tenant’s list. Other tenants can still attempt delivery to the same recipients.

In this post, you learn about the business problem this feature solves, how the new suppression precedence works, and how to implement tenant-level suppression for your multi-tenant email platform.

Quick reference

Item Detail
Feature Tenant-level suppression lists
Primary API operation PutTenantSuppressionAttributes
Scope options TENANT (isolated), ACCOUNT (shared, default)
Suppressed reasons BOUNCE, COMPLAINT, or both
Prerequisites Multi-tenancy enabled, production access
Key behavior Amazon SES evaluates exactly one suppression list per SendEmail call
Precedence order Configuration Set → Tenant → Account
Automatic recording Bounces → tenant list + global list. Complaints → tenant list only
Backward compatible Yes — opt-in per tenant, existing behavior unchanged

The cross-tenant suppression contamination problem in Amazon SES

Consider the following scenario. Imagine you run a SaaS marketing automation platform called “AnyCompany-SaaS.” You use Amazon SES multi-tenancy to send email on behalf of your customers (your tenants). For this example, consider Tenant A (a fast-growing fitness brand) and Tenant B (a conservative financial services company).

One day, Tenant A runs an aggressive, poorly targeted email campaign. Recipient A reports the email as spam, and that email address ([email protected]) gets added to your Amazon SES account-level suppression list to protect your sender reputation.

The problem? Tenant B has a perfectly valid, opted-in relationship with [email protected] and needs to send her a critical financial receipt. Before tenant-level suppression became available, AnyCompany-SaaS relied on the Amazon SES shared account-level suppression list. In this scenario, when Tenant B attempts to send email to [email protected], Amazon SES accepts the message but does not send it. The address is suppressed for every tenant in the account. Tenant B loses access to a valid recipient simply because of their neighbor’s poor email hygiene.

This is cross-tenant suppression contamination, and it creates several downstream problems:

  • Unfair deliverability outcomes — One tenant’s poor list hygiene affects all other tenants.
  • Increased support burden — Tenants ask “why is my email being suppressed?” and you have no clear answer.
  • Eroded trust — Your customers (the tenants) lose confidence in your platform’s email delivery capabilities.
  • Scaling challenges — The more tenants you add, the worse the contamination problem becomes.

Before today, the only workarounds were managing separate Amazon SES accounts per tenant (operationally expensive), or building custom suppression logic in your application layer (complex and error-prone). With Amazon SES tenant-level suppression lists, this shared-fate scenario is a thing of the past.

What is new: Tenant-level suppression lists

Each tenant in your account can now maintain its own isolated suppression list. When a hard bounce or complaint occurs for a tenant, Amazon SES records the suppressed address only on that tenant’s list. It does not add the address to other tenants’ lists.

Here is what this means in practice:

  • Isolation — Tenant A’s bounces and complaints affect only Tenant A’s suppression list.
  • Autonomy — Each tenant owns its own deliverability without impact from neighboring tenants.
  • Automatic management — Amazon SES automatically records entries based on hard bounces and complaints, and removes entries when recipients submit not-spam feedback.
  • Backward compatibility — Existing account-level suppression continues to work unchanged. Tenant-level suppression is opt-in per tenant.

Who benefits from tenant-level suppression?

This feature is designed for any organization that uses Amazon SES multi-tenancy to send email on behalf of multiple entities. Common use cases include:

  • SaaS platforms — Send transactional or marketing email for multiple customers, each with isolated suppression.
  • Marketing automation providers — Manage campaigns for different clients without cross-client contamination.
  • Enterprise multi-brand organizations — A corporation with multiple brands (for example, separate product lines or regional divisions) that need suppression isolation between brands.
  • Digital agencies — Manage email programs for dozens of clients under one Amazon SES account.
  • ISVs and resellers — Independent software vendors offering email capabilities as part of their platform.

When to use tenant-level vs. account-level suppression

Scenario Recommended scope Why
Single-tenant account (one brand, one sender) ACCOUNT No isolation needed — account-level works fine
Multi-tenant SaaS sending on behalf of customers TENANT Prevents cross-tenant contamination
Enterprise with multiple business units TENANT Each BU owns its deliverability independently
Per-workflow control within a single tenant Configuration set override Granular suppression at sub-tenant level
Migrating from separate Amazon SES accounts per tenant TENANT Consolidate into one account with isolation preserved

How Amazon SES tenant-level suppression precedence works

When you start mixing account-level lists, configuration sets, and tenant-level lists, it is important to understand how Amazon SES determines which list to check before sending an email. Amazon SES evaluates suppression rules in the following hierarchy (resolving to exactly one list).

Amazon SES suppression precedence resolving to one list: configuration set, then tenant, then account

Configuring suppression scope and suppressed reasons

Tenant-level suppression is controlled by two settings that you configure together:

  1. Suppression scope — Determines which suppression list Amazon SES checks at send time:
    • TENANT — Use the tenant’s own suppression list.
    • ACCOUNT — Use the account-level suppression list (this is the default).
  2. Suppressed reasons — Determines which events cause Amazon SES to automatically add addresses to the suppression list:
    • BOUNCE — Add addresses that produce hard bounces.
    • COMPLAINT — Add addresses that produce complaints.
    • Both BOUNCE and COMPLAINT — Add addresses for either event.

You configure both settings together using the PutTenantSuppressionAttributes API operation or by specifying SuppressionAttributes when creating a new tenant with CreateTenant.

Suppression precedence order

Behavior: Amazon SES evaluates exactly one suppression list per SendEmail call. The precedence is: Configuration Set > Tenant > Account. It does not check multiple lists in sequence.

Amazon SES resolves suppression settings using the following precedence order:

  1. Configuration set overrides (highest priority) — If the email is sent using a configuration set with a defined SuppressionOptions scope, Amazon SES uses that setting first.
  2. Tenant-level settings — If no configuration set override exists, and the email includes a TenantName, Amazon SES checks the isolated suppression list for that specific tenant.
  3. Account-level defaults (lowest priority) — If neither the configuration set nor the tenant specifies suppression settings, Amazon SES uses account-level defaults.

Important: An address that is on the account-level suppression list but not on the tenant’s list will not be suppressed when the scope is TENANT. Conversely, an address on the tenant’s list will not affect sends when the scope resolves to ACCOUNT.

Automatic suppression recording behavior

When the suppression scope is TENANT, Amazon SES automatically manages entries:

  • Hard bounces — Amazon SES adds the address to the tenant’s suppression list and the global suppression list. Amazon SES does not add the address to the account-level suppression list.
  • Complaints — Amazon SES adds the address to the tenant’s suppression list only.
  • Not-spam feedback — When a recipient marks a previously reported message as not spam, Amazon SES automatically removes COMPLAINT-reason entries from the tenant’s suppression list.

Prerequisites

Before implementing tenant-level suppression, make sure you have the following:

Required resources:

  1. An AWS account with Amazon SES configured.
  2. Multi-tenancy enabled with at least one tenant in your Amazon SES account.
  3. AWS Command Line Interface (AWS CLI) version 2 installed and configured with appropriate permissions.
  4. Production access (required for PutSuppressedDestination operations — sandbox accounts cannot manually add suppression entries).

Knowledge prerequisites: You should be familiar with Amazon SES account-level suppression concepts and multi-tenancy configuration.

Minimal example: Enable and send with tenant suppression

The following is the shortest path to enabling tenant-level suppression and sending an email that uses it:

# 1. Enable tenant suppression (bounces + complaints)
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE COMPLAINT

# 2. Send email with tenant context — SES checks MyTenant's suppression list
aws sesv2 send-email \
    --from-email-address [email protected] \
    --destination '{"ToAddresses":["[email protected]"]}' \
    --content '{"Simple":{"Subject":{"Data":"Hello"},"Body":{"Text":{"Data":"Test message"}}}}' \
    --tenant-name MyTenant

# 3. Verify — list entries on the tenant's suppression list
aws sesv2 list-suppressed-destinations \
    --tenant-name MyTenant

Implementation walkthrough

Implementing tenant-level suppression requires configuring your tenants and updating your sending API calls. Here is how to get started using the AWS CLI.

Step 1: Enable tenant-level suppression for an existing tenant

First, you need to configure the suppression attributes for a specific tenant. In this example, you enable suppression for both bounces and complaints for MyTenant:

aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE COMPLAINT

A successful request returns an HTTP 200 response with no body. Verify the configuration:

aws sesv2 get-tenant --tenant-name MyTenant

The response includes the suppression configuration:

{
    "Tenant": {
        "TenantName": "MyTenant",
        "TenantId": "tn-abc123def456",
        "SendingStatus": "ENABLED",
        "SuppressionAttributes": {
            "SuppressionScope": "TENANT",
            "SuppressedReasons": ["BOUNCE", "COMPLAINT"]
        }
    }
}

You can also configure suppression for a single reason type:

# Suppress bounces only
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE

# Suppress complaints only
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons COMPLAINT

Step 2: Create a new tenant with suppression enabled

If you are creating a new tenant, you can enable suppression from the start using the CreateTenant API operation:

aws sesv2 create-tenant \
    --tenant-name MyNewTenant \
    --suppression-attributes '{"SuppressionScope":"TENANT","SuppressedReasons":["BOUNCE","COMPLAINT"]}'

The response contains the new tenant’s ID:

{
    "TenantId": "tn-xyz789ghi012"
}

Step 3: Verify suppression is working

After configuring a tenant, verify that suppression entries are being recorded correctly. You can list entries on a tenant’s suppression list:

aws sesv2 list-suppressed-destinations \
    --tenant-name MyTenant

To check if a specific address is on a tenant’s suppression list:

aws sesv2 get-suppressed-destination \
    --email-address [email protected] \
    --tenant-name MyTenant

Step 4: Send email with tenant context

When sending email, include the TenantName parameter so that Amazon SES evaluates the correct suppression list:

aws sesv2 send-email \
    --from-email-address [email protected] \
    --destination '{"ToAddresses":["[email protected]"]}' \
    --content '{"Simple":{"Subject":{"Data":"Hello"},"Body":{"Text":{"Data":"Test message"}}}}' \
    --tenant-name MyTenant

Step 5: Manually manage suppression entries

You can manually add or remove entries from a tenant’s suppression list. This is useful for pre-loading known bad addresses or removing addresses that have been re-validated.

To add an entry:

aws sesv2 put-suppressed-destination \
    --email-address [email protected] \
    --reason BOUNCE \
    --tenant-name MyTenant

To remove an entry:

aws sesv2 delete-suppressed-destination \
    --email-address [email protected] \
    --tenant-name MyTenant

Advanced: Configuration set overrides for per-workflow suppression control

For scenarios where you need per-workflow suppression control within a tenant, you can override tenant suppression settings at the configuration set level:

aws sesv2 create-configuration-set \
    --configuration-set-name my-config-set \
    --suppression-options '{"SuppressionScope":"TENANT","SuppressedReasons":["BOUNCE"]}'

You can also update an existing configuration set:

aws sesv2 put-configuration-set-suppression-options \
    --configuration-set-name my-config-set \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE

Key considerations

Keep the following points in mind as you implement tenant-level suppression:

  • Sandbox restrictions — You cannot call PutSuppressedDestination while your account is in the Amazon SES sandbox. Request production access first. Note that this restriction only applies to manually adding entries. Automatic suppression from bounces and complaints works in sandbox mode.
  • Entries persist — Disabling tenant-level suppression does not delete existing entries from the tenant’s suppression list. If you re-enable tenant-level suppression later, those entries are still active.
  • Fail-close behavior — If the tenant suppression service is unavailable, Amazon SES suppresses the message rather than allowing it through.
  • The “no tenant” fallback — If you enable tenant-level suppression across your architecture but inadvertently miss updating a legacy microservice, any SendEmail call made without a TenantName parameter automatically falls back to evaluating your shared account-level suppression list.
  • Migration strategy — We recommend a phased migration. Start by configuring tenant-level suppression for new tenants or low-volume tenants first. Monitor their isolated lists using the ListSuppressedDestinations API before updating the SendEmail calls for your highest-volume legacy tenants.

Check the Amazon SES Developer Guide for the latest supported actions and service quotas.

Disabling tenant-level suppression

If you need to return a tenant to account-level suppression, you have two options:

Option 1: Explicitly set the scope to ACCOUNT:

aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope ACCOUNT \
    --suppressed-reasons BOUNCE COMPLAINT

Option 2: Clear all suppression settings:

aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant

When you omit both --suppression-scope and --suppressed-reasons, Amazon SES clears the tenant’s suppression settings, and the tenant falls back to account-level suppression behavior.

Cleaning up

If you followed along with this walkthrough and want to remove the resources you created, take the following steps:

Important: Disabling tenant-level suppression does not delete existing suppression entries. If you plan to re-enable this feature later, be aware that previously suppressed addresses remain on the tenant’s list.

  1. Clear tenant suppression settings (returns the tenant to account-level behavior):
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant
  1. If you created a test tenant, delete it:
aws sesv2 delete-tenant --tenant-name MyNewTenant
  1. If you created a configuration set for testing, delete it:
aws sesv2 delete-configuration-set \
    --configuration-set-name my-config-set

FAQ

Q: Does tenant-level suppression replace account-level suppression?

A: No. Account-level suppression continues to work unchanged. Tenant-level suppression is opt-in. You enable it per tenant by setting the suppression scope to TENANT. Tenants without this configuration continue using the account-level suppression list.

Q: What happens if I send an email without a TenantName parameter after enabling tenant-level suppression?

A: The email falls back to account-level suppression evaluation. Amazon SES only checks a tenant’s isolated suppression list when the SendEmail call includes the TenantName parameter and that tenant has SuppressionScope set to TENANT.

Q: Are existing suppression entries deleted when I disable tenant-level suppression for a tenant?

A: No. Entries persist on the tenant’s suppression list. If you re-enable tenant-level suppression later, those entries become active again. To remove entries, you must explicitly call DeleteSuppressedDestination for each address.

Q: Can a single email address appear on both the account-level and a tenant-level suppression list?

A: Yes. The same address can exist on multiple lists. However, Amazon SES only checks the list that the resolved scope points to. If the scope is TENANT, only the tenant’s list is evaluated. The account-level list is not consulted.

Q: Does tenant-level suppression work in the Amazon SES sandbox?

A: Automatic suppression recording (from bounces and complaints) works in sandbox mode. However, you cannot manually add entries using PutSuppressedDestination until you request production access.

Q: How do I migrate from separate Amazon SES accounts per tenant to a single account with tenant-level suppression?

A: We recommend a phased approach: (1) Create tenants in your consolidated account, (2) Enable tenant-level suppression for each, (3) Export suppression entries from the old accounts using ListSuppressedDestinations, (4) Import them into the new tenant lists using PutSuppressedDestination, (5) Update your sending logic to include TenantName in all SendEmail calls.

Q: What is the maximum number of entries on a tenant’s suppression list?

A: Tenant-level suppression lists follow the same limits as account-level suppression lists. Check the Amazon SES quotas page for current limits.

Conclusion

Tenant-level suppression lists give ISVs, SaaS platforms, and large enterprises the granular control they need to manage email deliverability fairly and effectively. No more shared suppression lists causing cross-tenant contamination, and no more tenants losing access to valid recipients because of a neighbor’s email hygiene problems. Each tenant now owns their reputation data independently.

To get started:

  1. Using tenant-level suppression lists in Amazon SES.
  2. PutTenantSuppressionAttributes API reference.
  3. Using the Amazon SES account-level suppression list.

You can also configure and manage tenant-level suppression directly from the Amazon SES console.

If you have questions or feedback, reach out to us on AWS re:Post or through your AWS account team. We look forward to hearing how you are using tenant-level suppression to improve your multi-tenant email platform.


About the author

Introducing Apache Spark Connect support in AWS Glue interactive sessions

Post Syndicated from Zach Mitchell original https://aws.amazon.com/blogs/big-data/introducing-apache-spark-connect-support-in-aws-glue-interactive-sessions/

When we built AWS Glue interactive sessions, our goal was to make AWS Glue as interactive as running local Python from a notebook. We mostly succeeded. With a straightforward Python package and a Jupyter notebook, you could execute remotely against the AWS Glue ephemeral Spark backend. The Livy-based approach was ahead of its time, but it had limitations from its REST-based protocol. Running local PySpark unlocked powerful integrated development environment (IDE) features such as debugging and linting, so your environment could understand the code and help you develop Spark applications more quickly. Customers would often split their development work. They used local Spark (or Docker containers) to develop in an IDE on a small amount of data, then switched to AWS Glue interactive sessions to validate scaling and tuning against the full dataset.

With modern PySpark releases came a new protocol: Apache Spark Connect. Spark Connect bridges the gap between these two worlds: you develop in local Python, but execute on AWS Glue against actual data. Today, AWS Glue interactive sessions support Spark Connect natively. You can connect from any environment that supports the PySpark remote() API, including VS Code, PyCharm, Amazon SageMaker Unified Studio notebooks, and standalone Python applications. You don’t need to install specialized kernels or manage cluster infrastructure.

What Spark Connect changes

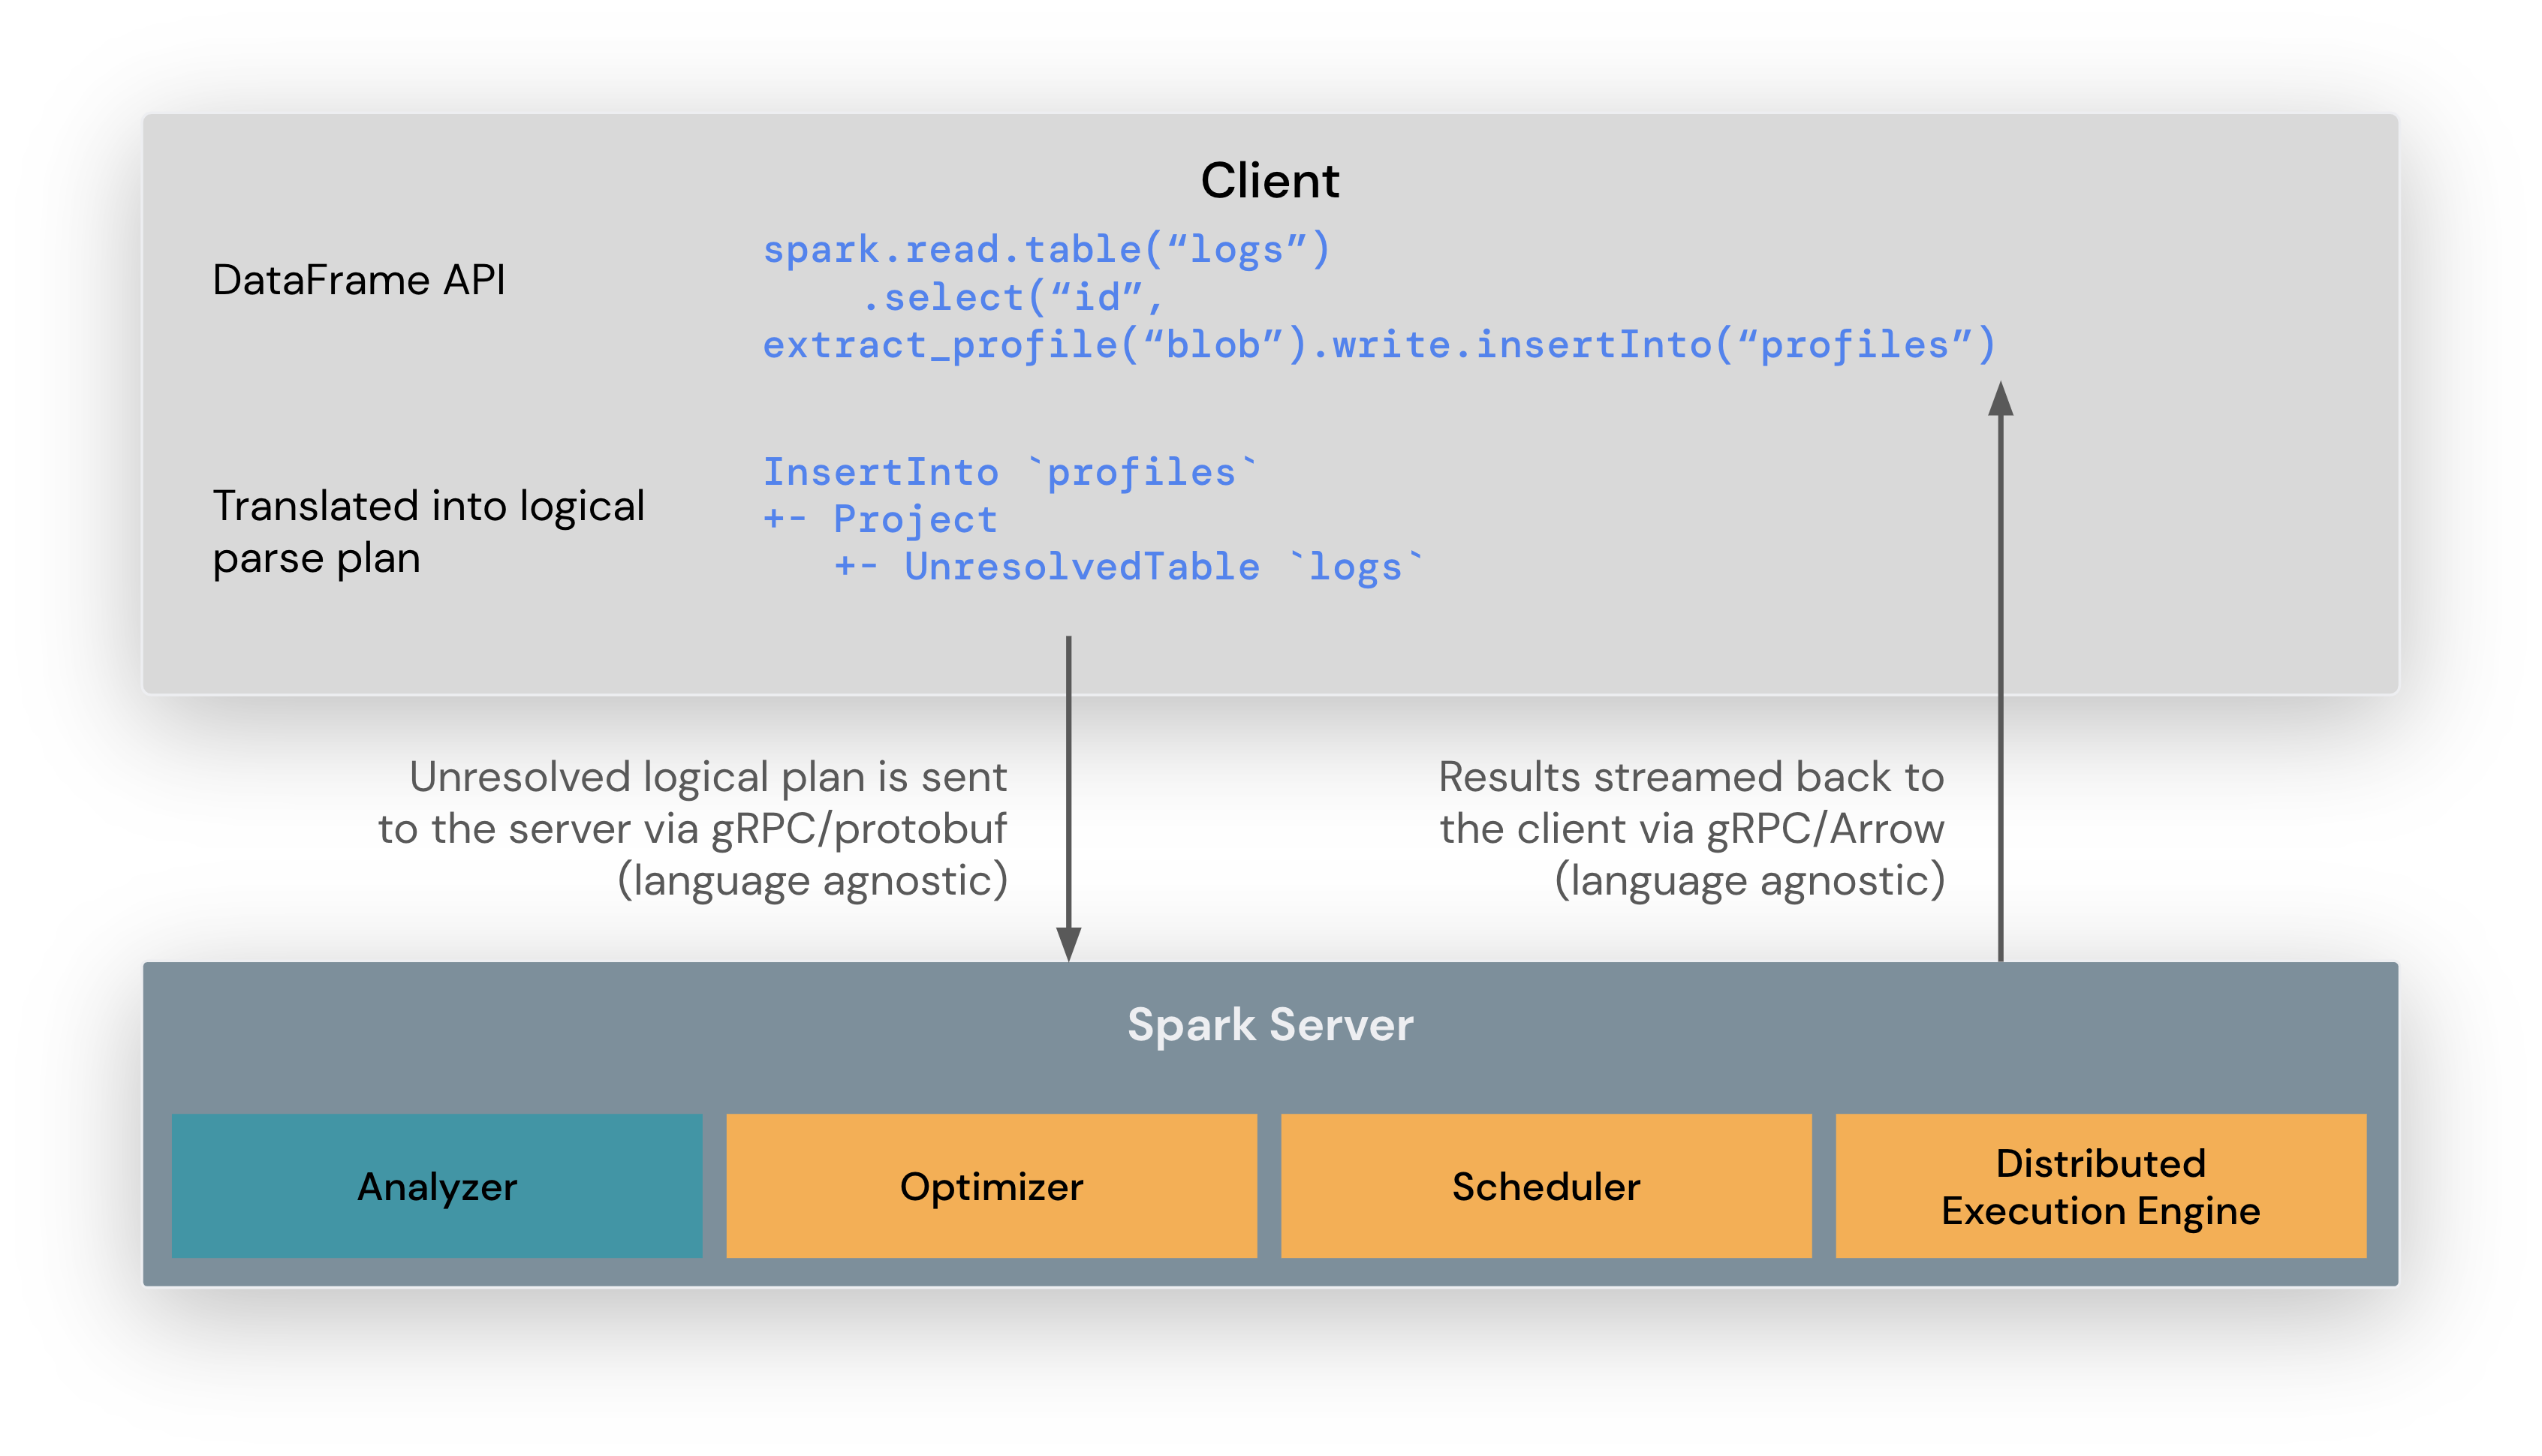
Spark Connect, introduced in Spark 3.4, decouples the Spark client from the server through a lightweight gRPC protocol. Instead of running your driver program on the cluster, your IDE communicates with a remote Spark server through a thin client layer. This architecture unlocks the key workflow improvement: you develop locally and execute remotely.

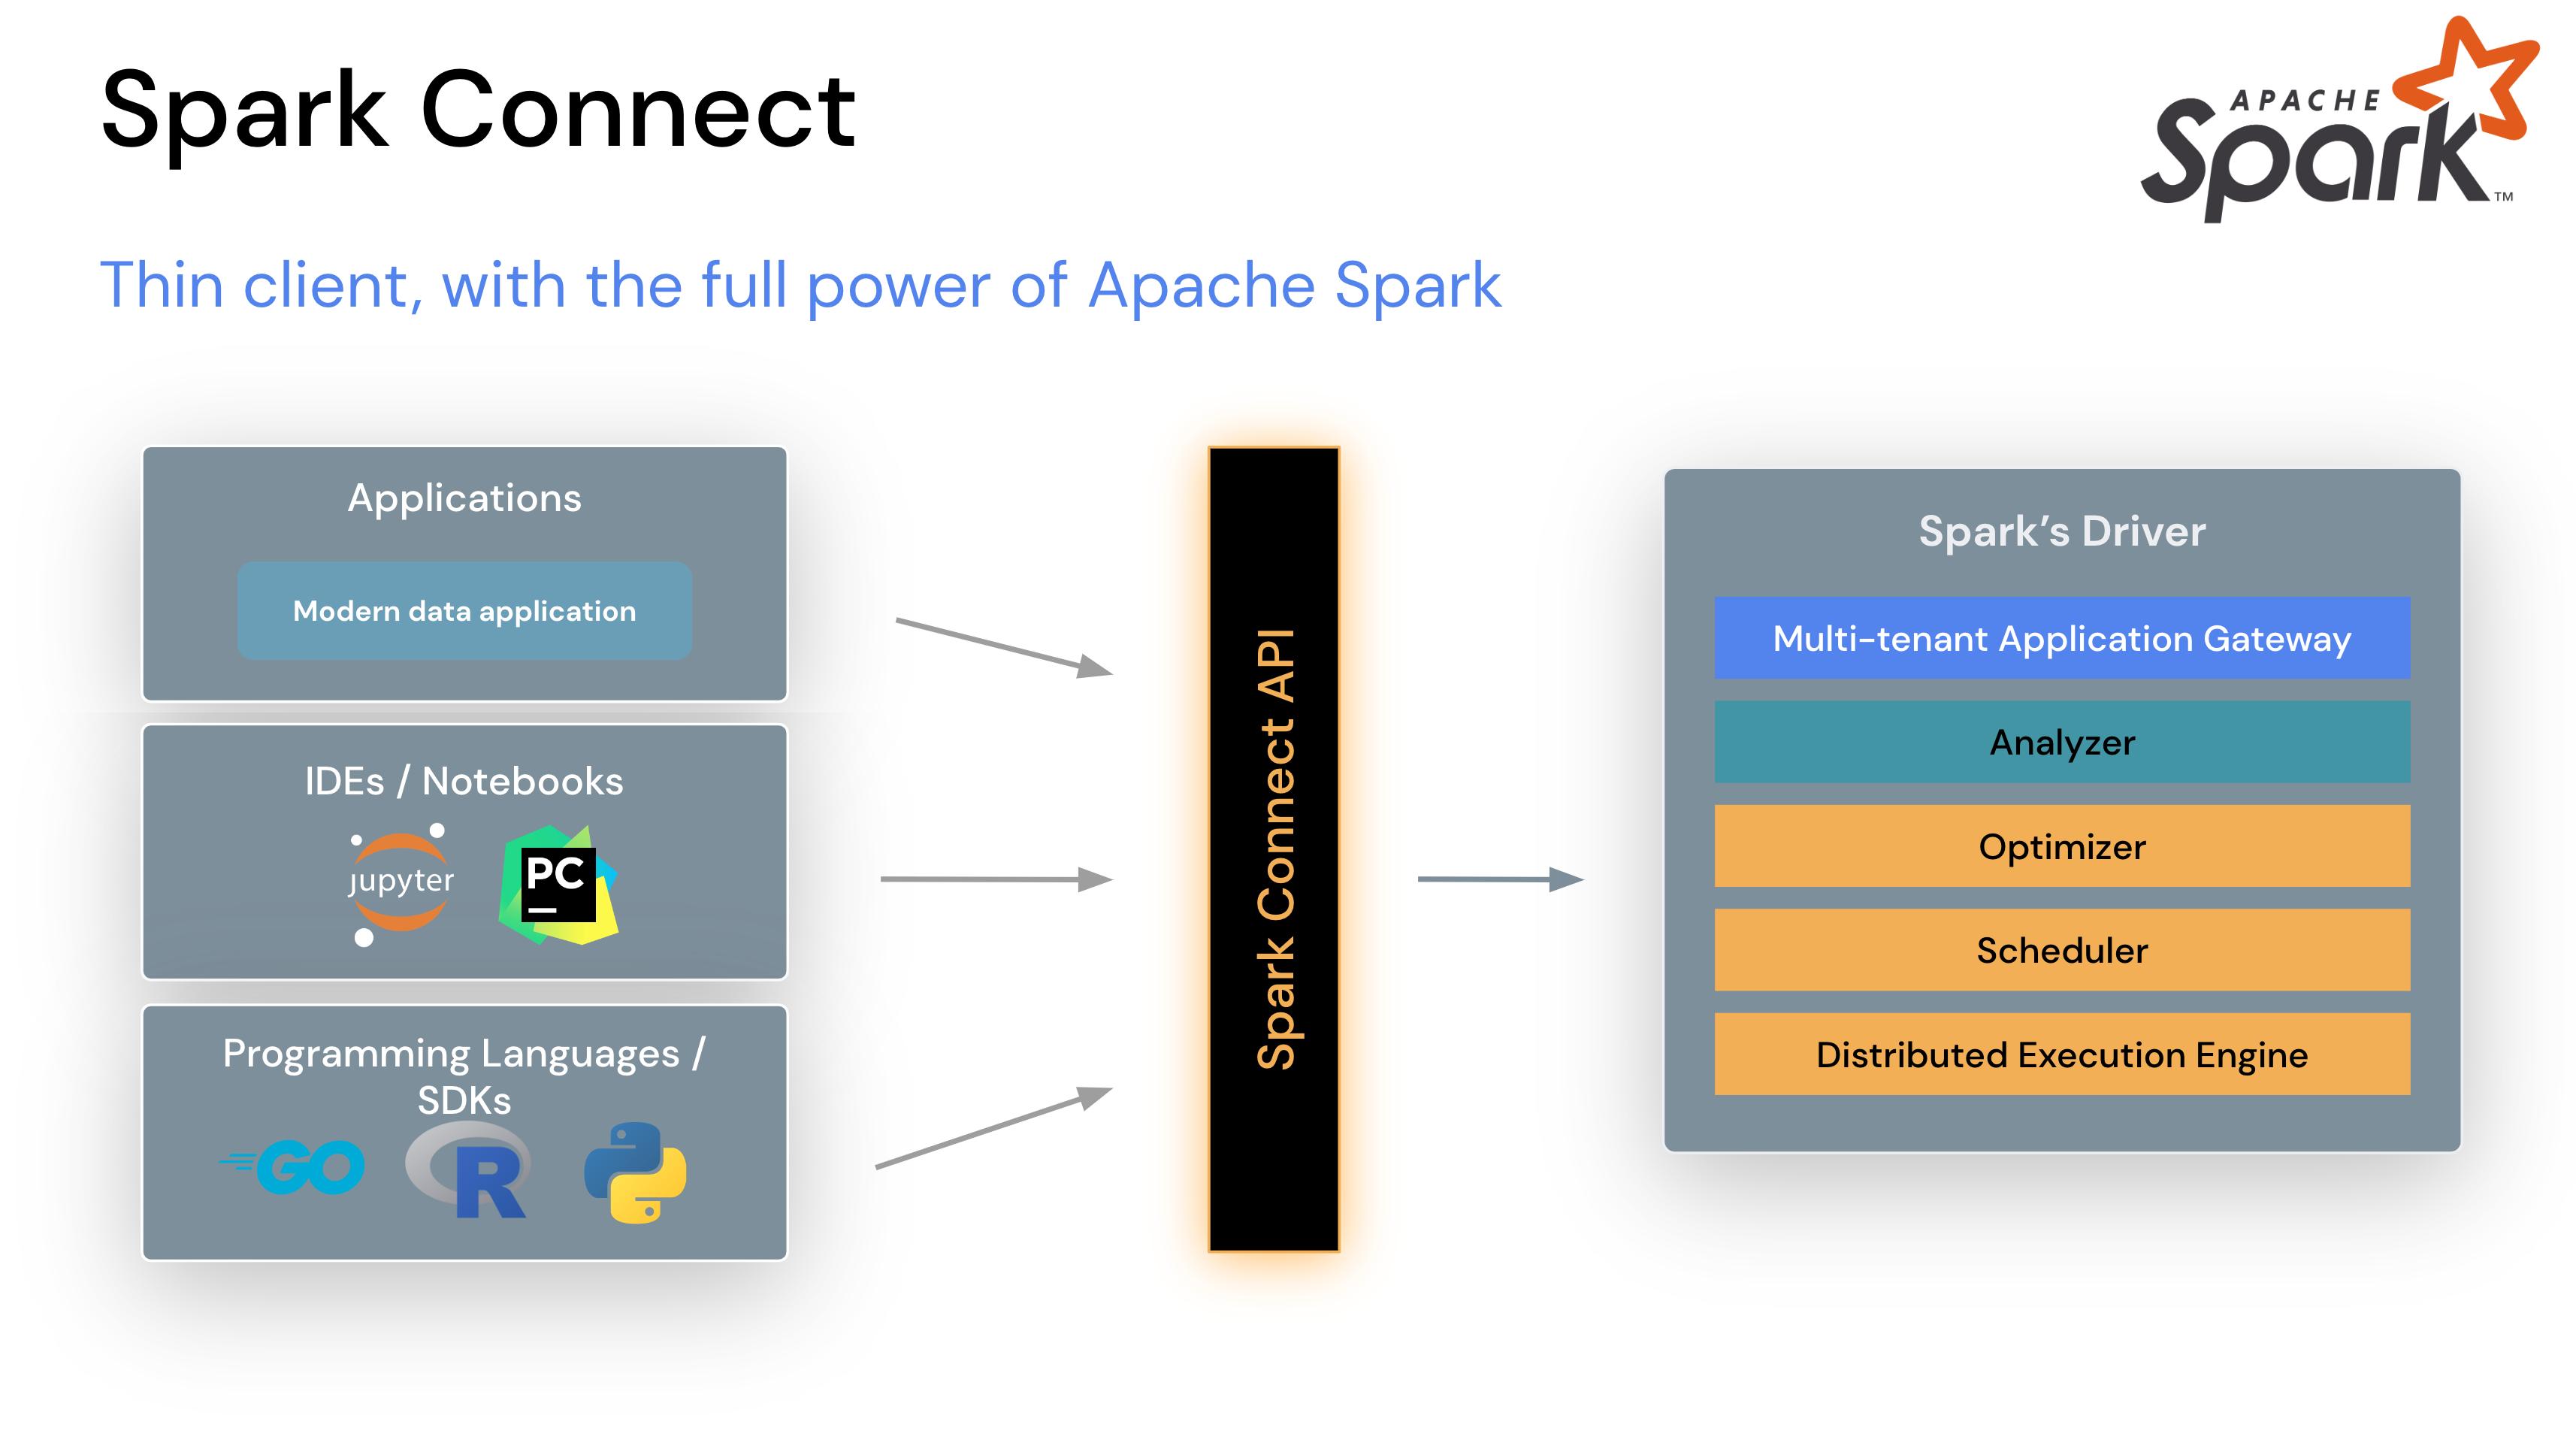
Spark Connect architecture diagram showing a thin client communicating with a remote Apache Spark server

Spark Connect architecture — thin client with the full power of Apache Spark

With Spark Connect support in AWS Glue interactive sessions, you get:

  • IDE freedom – Use VS Code, PyCharm, JupyterLab, or any Python environment. No kernel installation required.
  • Programmatic access – Build Spark into your Python applications and automation scripts with a standard SparkSession.builder.remote() call.
  • Serverless execution – AWS Glue provisions and manages the Spark cluster. You pay only for the data processing units (DPUs) consumed while your session is active.
  • Spark Connect monitoring – The Spark Live UI now includes a dedicated Connect tab showing active Spark Connect sessions and operations alongside the existing Jobs, Stages, and Executors views.

Getting started with SageMaker Unified Studio

Amazon SageMaker Unified Studio provides the most direct path to Spark Connect on AWS Glue. The notebook environment handles session creation, endpoint retrieval, and token refresh automatically, so no connection boilerplate is required.

Prerequisite: You need an Amazon SageMaker Unified Studio project to use this workflow. If you don’t have one, create a project in your SageMaker Unified Studio domain first.

To connect to an AWS Glue Spark Connect session:

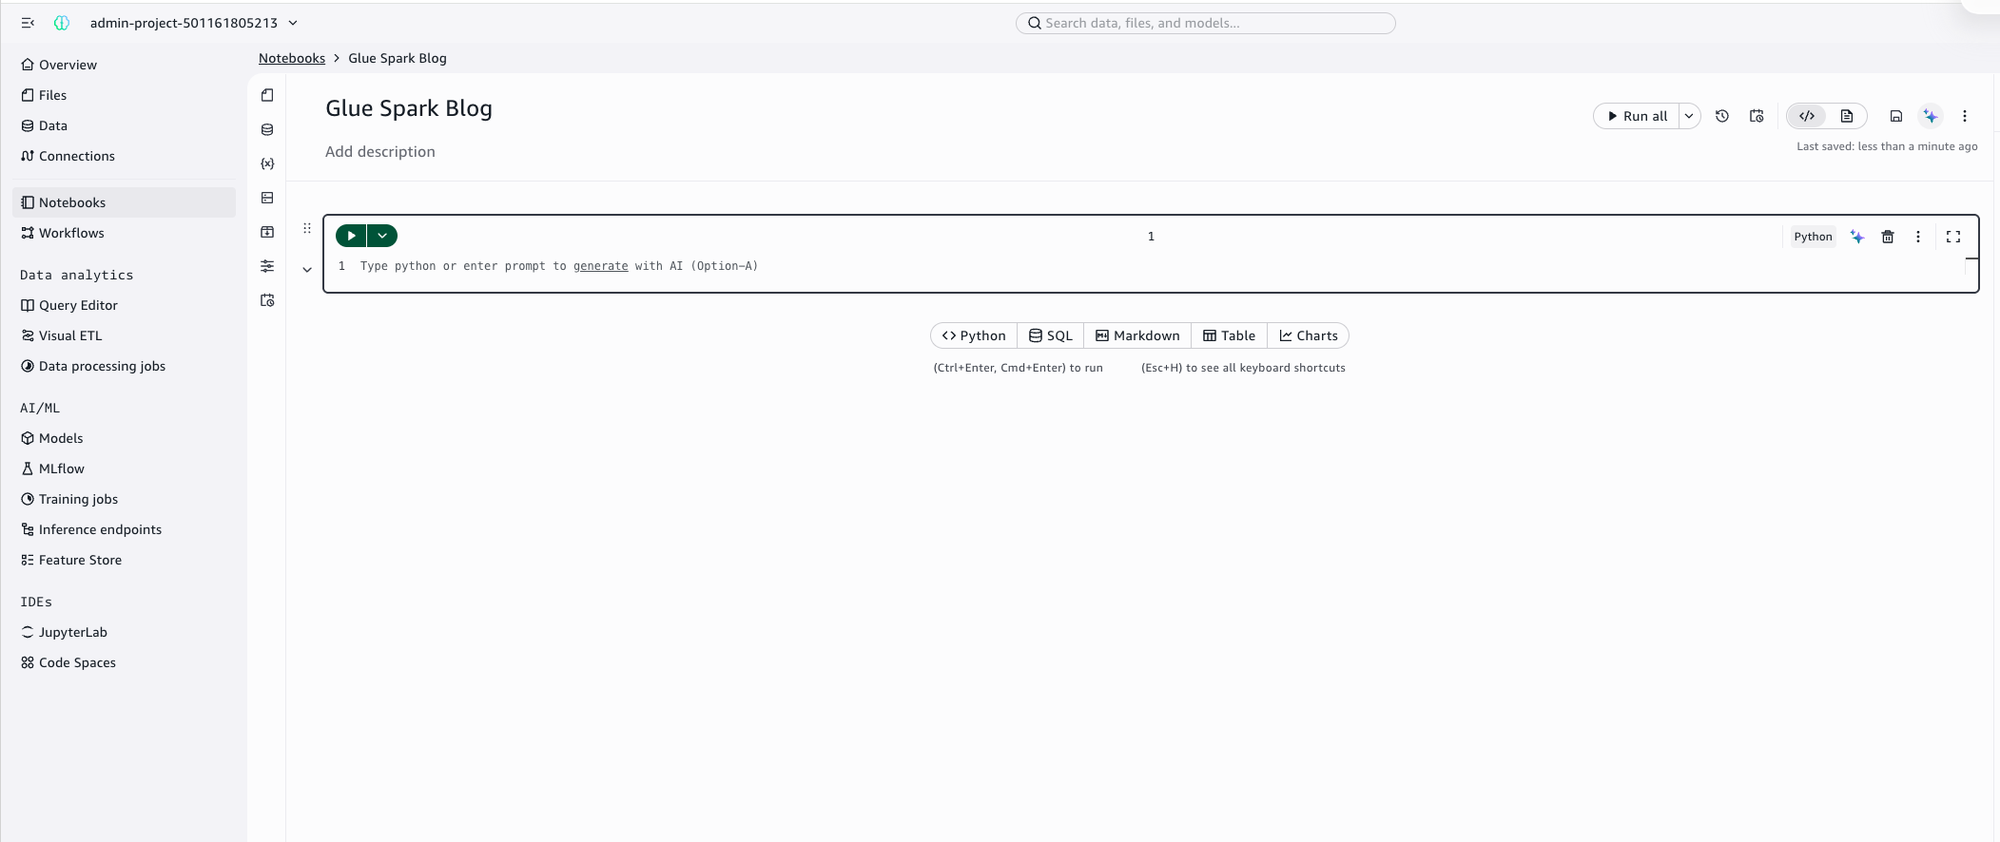
  1. Sign in to SageMaker Unified Studio, choose your project, and create or open a Notebook.

A notebook open in SageMaker Unified Studio

A notebook open in SageMaker Unified Studio

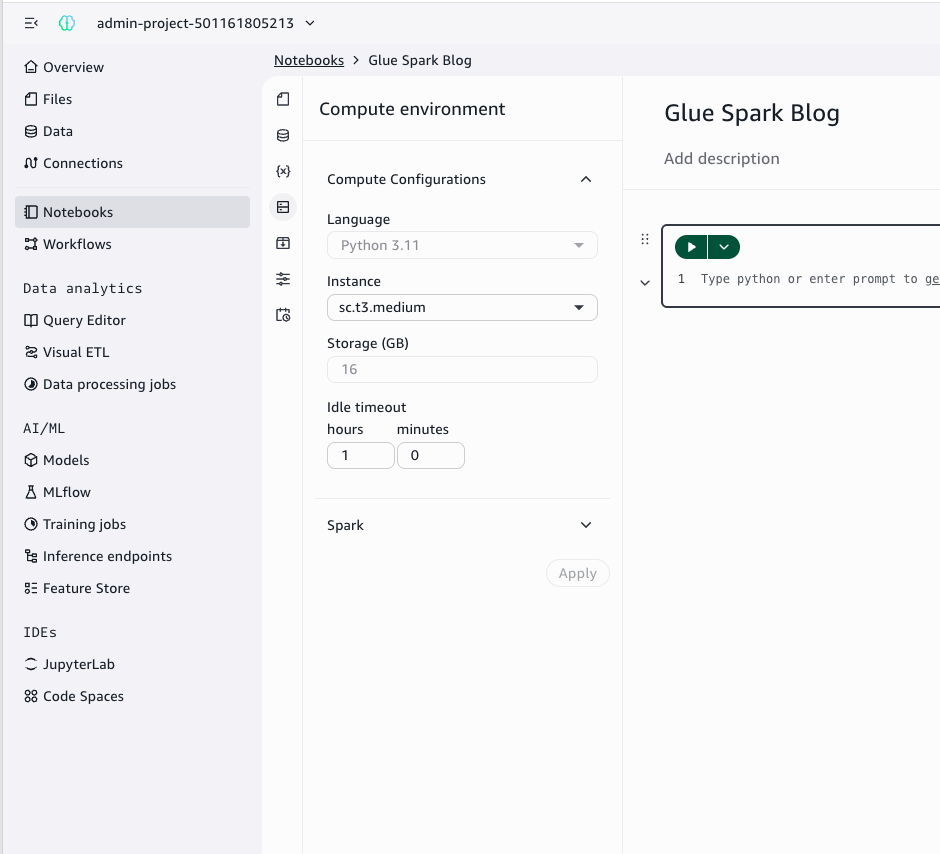
  1. Choose the compute icon in the left toolbar to open the Compute environment panel. Expand the Spark section.

Compute environment panel in SageMaker Unified Studio with the Spark section expanded

The Compute environment panel with the Spark dropdown list

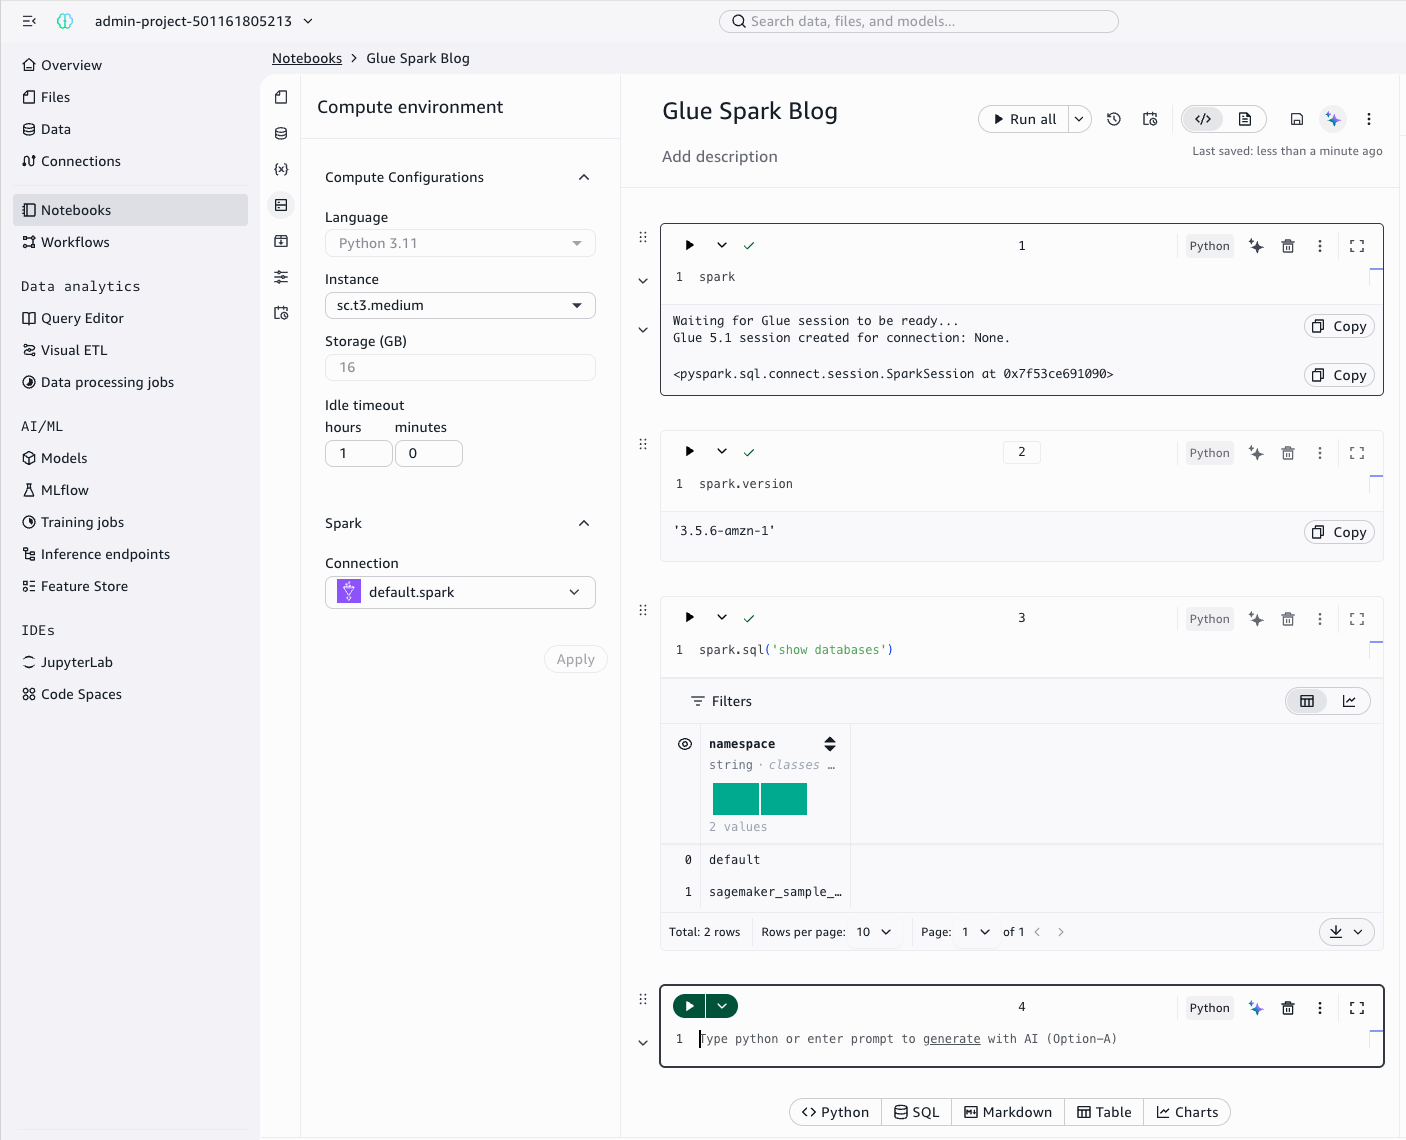
  1. Select a Glue Spark connection. Depending on your SageMaker domain configuration, you will see either default.spark or named connections such as project.spark.compatibility. Select the appropriate Glue (Spark) connection and choose Apply.

Notebook cell showing spark.version returns 3.5.6-amzn-1 after connecting to Glue Spark Connect

Connected to Glue Spark Connect — running spark.version returns ‘3.5.6-amzn-1’

After you make your selection, you’re connected. The spark session object is available natively. No imports or configuration are needed. Start running PySpark immediately:

spark.sql("SHOW DATABASES").show()

The session manages itself in the background, including automatic token refresh.

Using the sagemaker_studio SDK

The sagemaker-studio Python package extends the Spark Connect experience beyond SageMaker Unified Studio notebooks into local IDEs, continuous integration and continuous delivery (CI/CD) pipelines, and any Python environment. The sparkutils module handles session initialization and connection configuration in a single call. You get the same streamlined experience as in the notebook, anywhere you run Python:

from sagemaker_studio import sparkutils

# Initialize a Glue Spark Connect session using your project connection
spark = sparkutils.init(connection_name="default.spark")

# Run queries immediately
spark.sql("SHOW DATABASES").show()

You can also use sparkutils.get_spark_options() to retrieve pre-configured Java Database Connectivity (JDBC) options for reading and writing to data sources through your project connections. Supported sources include Amazon Redshift, Amazon Aurora, and Amazon DocumentDB (with MongoDB compatibility):

# Get connection options for a Redshift connection in your project
options = sparkutils.get_spark_options("my_redshift_connection")

# Read from Redshift via Spark Connect
df = spark.read.format("jdbc").options(**options).option("dbtable", "analytics.orders").load()
df.show()

Within SageMaker Unified Studio, the sagemaker-studio SDK is native to the environment. The spark session and sparkutils are available without installation. For local IDE use, install it with pip install sagemaker-studio and configure credentials through an AWS named profile or boto3 session.

How it works

Spark Connect sessions in AWS Glue use a three-step workflow:

  1. Create a session – Call the CreateSession API with SessionType set to SPARK_CONNECT. The session provisions in approximately 30 seconds.
  2. Retrieve the endpoint – Call GetSessionEndpoint to receive a sc:// gRPC endpoint URL and a time-limited authentication token.
  3. Connect with PySpark – Pass the endpoint and token to SparkSession.builder.remote() and start running Spark operations.

Spark Connect protocol flow from the DataFrame API to a logical plan, sent over gRPC and protobuf, with results streamed back over gRPC and Arrow

Spark Connect protocol flow — DataFrame API translated to logical plan, sent via gRPC/protobuf, results streamed back via gRPC/Arrow

Connecting with the low-level API

Some environments don’t have the sagemaker-studio SDK, such as custom containers, AWS Lambda functions, or non-Python toolchains. In these environments, or if you’re not using SageMaker Unified Studio, you can use the AWS SDK (Boto3) to manage sessions directly. The following example demonstrates the full workflow:

import time, boto3, urllib.parse
from pyspark.sql import SparkSession

glue = boto3.client("glue", region_name="us-east-1")

# 1. Create a Spark Connect session
session_id = "my-spark-connect-session"
glue.create_session(
    Id=session_id,
    Role="arn:aws:iam::123456789012:role/GlueServiceRole",
    Command={"Name": "glueetl"},
    GlueVersion="5.1",
    SessionType="SPARK_CONNECT",
    DefaultArguments={"--enable-spark-live-ui": "true"},
)

# 2. Wait for the session to reach READY
while True:
    status = glue.get_session(Id=session_id)["Session"]["Status"]
    if status == "READY":
        break
    time.sleep(5)

# 3. Get the Spark Connect endpoint
sc = glue.get_session_endpoint(SessionId=session_id)["SparkConnect"]
endpoint_url = sc["Url"]
auth_token = sc["AuthToken"]

# 4. Connect with PySpark
encoded_token = urllib.parse.quote(auth_token, safe="")
connection_string = f"{endpoint_url}:443/;use_ssl=true;x-aws-proxy-auth={encoded_token}"
spark = SparkSession.builder.remote(connection_string).getOrCreate()
spark.sql("SELECT 1 + 1 AS result").show()

Monitoring with Spark Live UI

When you enable the Spark Live UI at session creation, you gain access to a real-time dashboard showing:

  • Jobs and Stages – Track active, completed, and failed jobs with stage-level metrics.
  • Executors – Monitor memory usage, shuffle data, and executor health.
  • SQL – Inspect query plans and execution details.
  • Connect tab – View active Spark Connect sessions and operations (specific to Spark Connect).

Access the dashboard through the GetDashboardUrl API or directly from the AWS Glue console.

import boto3, webbrowser

glue = boto3.client("glue", region_name="us-east-1")
dashboard = glue.get_dashboard_url(
    ResourceId="my-spark-connect-session",
    ResourceType="SESSION",
)
webbrowser.open(dashboard["Url"])

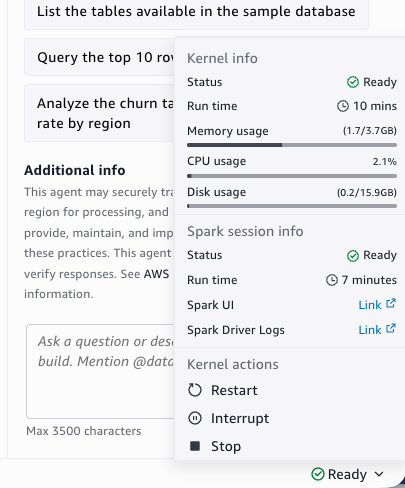
In SageMaker Unified Studio, no API call is needed. Choose Ready in the notebook status bar to open the kernel info popover. From there, open the Spark UI link for the live dashboard or Spark Driver Logs for real-time log output.

Notebook status bar Ready button that opens the Spark UI and Spark Driver Logs links

Image showing “Ready” in the status bar to access Spark UI and Driver Logs directly from the notebook

Token refresh

Authentication tokens expire after 30 minutes. In SageMaker Unified Studio, this is handled automatically. For programmatic use, you can use a background thread to keep the connection alive. The following helper reconnects transparently before the token expires:

import threading, time, boto3, urllib.parse
from pyspark.sql import SparkSession

class GlueSparkConnect:
    """Maintains a SparkSession with automatic token refresh."""

    def __init__(self, session_id, region="us-east-1", refresh_margin=300):
        self.session_id = session_id
        self.glue = boto3.client("glue", region_name=region)
        self.refresh_margin = refresh_margin  # seconds before expiry to refresh
        self._lock = threading.Lock()
        self.spark = self._connect()
        self._start_refresh_loop()

    def _connect(self):
        sc = self.glue.get_session_endpoint(SessionId=self.session_id)["SparkConnect"]
        encoded_token = urllib.parse.quote(sc["AuthToken"], safe="")
        remote_url = f"{sc['Url']}:443/;use_ssl=true;x-aws-proxy-auth={encoded_token}"
        self._token_expiry = sc["AuthTokenExpirationTime"].timestamp()
        return SparkSession.builder.remote(remote_url).getOrCreate()

    def _start_refresh_loop(self):
        def _loop():
            while True:
                sleep_for = max(self._token_expiry - time.time() - self.refresh_margin, 30)
                time.sleep(sleep_for)
                with self._lock:
                    self.spark = self._connect()
        t = threading.Thread(target=_loop, daemon=True)
        t.start()

# Usage
session = GlueSparkConnect("my-spark-connect-session")
session.spark.sql("SELECT 1 + 1 AS result").show()

The background thread sleeps until 5 minutes before token expiry, then transparently reconnects. Because the daemon thread exits when your script ends, there is no cleanup required.

Getting started

To start using Spark Connect with AWS Glue interactive sessions:

  1. Use AWS Glue version 5.1 (Apache Spark 3.5.6).
  2. Install PySpark 3.5.6 locally: pip install pyspark==3.5.6.
  3. Grant your AWS Identity and Access Management (IAM) identity permissions for glue:CreateSession, glue:GetSession, and glue:GetSessionEndpoint.
  4. Create a session with --session-type SPARK_CONNECT and connect from your preferred environment.

VPC note: If you connect to AWS Glue interactive sessions through a virtual private cloud (VPC) endpoint, add the new Spark Connect endpoint (com.amazonaws.{region}.glue.sessions) to your VPC configuration. Existing AWS Glue VPC endpoints don’t cover Spark Connect traffic.

For detailed instructions, see Connecting to a Spark Connect session in the AWS Glue Developer Guide.


About the authors

Zach Mitchell

Zach Mitchell

Zach is a Senior Big Data Architect at AWS Worldwide Specialist Organization for Analytics. He works with customers to design and build data applications on AWS, with a focus on SageMaker Unified Studio, AWS Glue, and AWS Lake Formation. Outside of work, he enjoys building things with code and occasionally writing about it.

Shrey Malpani

Shrey Malpani

Shrey is a Senior Technical Product Manager at AWS Analytics. He is focused on building and scaling data processing, data integration, and data management capabilities across services like AWS Glue, Amazon EMR, and Amazon Redshift that help customers build AI-ready data platforms for their analytics or machine learning workflows.

Vaibhav Naik

Vaibhav Naik

Vaibhav is a Software Engineer at AWS Glue, where he leads the development of enterprise Generative AI managed services and Agentic data systems. He has over a decade of experience designing massive-scale cloud infrastructure and distributed computing platforms.

Tom Olson

Tom Olson

Tom is a Software Development Engineer on the AWS Glue team, focused on Interactive Sessions and operational excellence. He brings over 20 years of software development experience, including government contracting and EC2 Networking at AWS. Outside of work, he enjoys running and playing board games.

Gaurav Krishnan

Gaurav Krishnan

Gaurav is a Software Development Engineer at AWS Glue. He has a deep interest in distributed systems and creating low-friction developer experiences for interactive data workloads on Apache Spark. In his spare time, he enjoys running and trying new restaurants.

AI Can Now Execute 73% of Expert-Level Cyberattacks. Here’s What IT Leaders Need to Do.

Post Syndicated from Kari Wilson original https://www.backblaze.com/blog/ai-can-now-execute-73-of-expert-level-cyberattacks-heres-what-it-leaders-need-to-do-now/

An illustration of a laptop screen and a lock.

On April 7, 2026, Anthropic announced a model so capable they refused to release it publicly. Claude Mythos, their most advanced frontier AI, was deemed too dangerous for open access because of one thing: it can hack.

Not in the vague, theoretical sense that security researchers worry about. In the “completed 73% of expert-level capture-the-flag challenges that no AI could touch before April 2025” sense. In the “autonomously identified a 17-year-old remote code execution vulnerability in FreeBSD from scratch, without a human involved after the initial prompt” sense. In the “found thousands of critical zero-days across every major operating system and web browser in a matter of weeks” sense.  

Anthropic locked Claude Mythos behind Project Glasswing, a vetted partner program initially restricted to roughly 50 organizations—AWS, Microsoft, Google, Apple, Cisco, CrowdStrike, and others—to use the model for defensive work before adversaries could develop equivalent capability. By June, that program had expanded to more than 200 organizations across 15 countries, including operators of power grids, water systems, hospitals, and telecommunications infrastructure. 

Then, on June 9, Anthropic released Fable 5—the first public version of a Mythos-class model—equipped with safeguards that reroute higher-risk queries to less-capable models. The same day, it released Claude Mythos 5 directly to vetted Glasswing partners. Later in June, after a brief US government export review, the Commerce Department confirmed that “appropriate safeguards are in place” and permitted Anthropic to redeploy Mythos 5 to trusted cyber defenders. 

But here’s the part that should be on every IT leader’s radar: Anthropic itself now projects that other AI companies will have Mythos-class models within six to 12 months, and those companies may not ship with equivalent safeguards. 

GPT-5.5, released three weeks later, didn’t wait. OpenAI shipped it with expanded cybersecurity capabilities and its own controlled-access program—also designed for defense, also eventually available to people with different intentions. 

The AI arms race in cybersecurity isn’t coming. It’s here.

Ransomware 5.0 Doesn’t Need a Skilled Operator

For most of its history, ransomware required a human being at the keyboard: someone doing reconnaissance, identifying targets, crafting phishing lures, moving laterally through a network. Skilled attackers commanded significant ransoms. Amateur operators made rookie mistakes.

That dynamic is collapsing.

Ransomware now appears in 48% of all breach chains, according to the Verizon 2026 Data Breach Investigations Report—up from 44% the year prior. Active ransomware groups jumped 49% year over year. Over 250 new operators entered the market in just the last six months, many of them low-skill actors using generative AI to craft personalized phishing campaigns 60% faster than was possible before. AI-assisted lateral movement was present in over 65% of recent cases.

The Verizon 2026 DBIR also marks a shift in how attackers get in the door: for the first time, exploiting unpatched software vulnerabilities has overtaken stolen credentials as the number one initial access vector, now responsible for 31% of breaches. That’s not a coincidence in a world where AI can scan codebases for exploitable flaws at machine speed.

IBM’s 2026 X-Force Threat Index confirmed that “collapsing barriers to entry” are letting even low-volume operators run campaigns that overwhelm defenders. The average cost of a data breach in the US hit $10.22 million—an all-time record. 

Trend Micro’s 2026 security predictions describe what they call “Ransomware 5.0”: a model where AI handles reconnaissance, vulnerability scanning, lateral movement, and even ransom negotiation autonomously, without a human operator directing any of it.

If you’re still designing your security posture around slowing down a skilled human attacker, you’re fighting the last war.

The Thing Nobody Wants to Say Out Loud

Here’s where I’m going to say something a little uncomfortable: the cybersecurity industry has been selling you detection for years when what you actually needed was recovery.

Detection is important. Don’t get me wrong. But detection-centric security assumes you catch the attack before it fully executes. In an era where AI compresses the attack timeline, exploit chains run at machine speed, and hundreds of new ransomware groups just showed up with AI-powered toolkits, detection alone isn’t a resilience strategy. It’s a bet.

The UK Government’s AI Security Institute tested Claude Mythos extensively and confirmed it cannot reliably execute attacks against organizations with well-hardened defenses. That’s genuinely good news. But it raises an obvious follow-up question: how many organizations actually have well-hardened defenses? A 2025 report found that over 45% of discovered security vulnerabilities in large organizations go unpatched after 12 months. Many critical infrastructure operators still run end-of-life software.

The honest answer is: most organizations are not that hardened. And even the ones that are will face a more capable threat next year than they face today.

This is why immutable backups aren’t just a box to check; they’re the safeguard that functions even when everything else fails. If an attacker encrypts your production environment before detection fires, the question isn’t “how did that happen?” It’s “how fast can you recover?”

What Claude Mythos Actually Changes (And What It Doesn’t)

It’s worth separating signal from noise here, because the coverage of Claude Mythos has ranged from measured to apocalyptic.

What Mythos changes: the technical barrier for sophisticated attacks. Vulnerabilities that previously required elite researchers to discover and weaponize can now be found and chained faster. Anthropic’s own red team found that Mythos could identify and exploit a previously unknown FreeBSD remote code execution vulnerability—fully autonomously, no human involved after the initial prompt. Across all Project Glasswing partners, Mythos has now surfaced more than 10,000 high- or critical-severity security flaws in production codebases. That means the window between vulnerability disclosure and active exploitation, already dangerously short, gets shorter. It also means less-skilled threat actors get access to capabilities that used to require significant expertise.

What Mythos doesn’t change: the fundamental anatomy of a ransomware attack. Attackers still need initial access. The Verizon 2026 DBIR confirms they’re still relying on unpatched software, stolen credentials, and phishing as entry points just finding and exploiting them faster.  Once inside, they still need to move laterally, identify high-value data, and execute the encryption sequence. The Centre for Emerging Technology and Security at the Alan Turing Institute made this point clearly: more sophisticated ransomware attacks that rely on stolen credentials, social engineering, or already-compromised accounts are “far less likely to be affected” by Mythos-class models on either side.

That matters for how you defend. Hardening access controls, enforcing MFA, patching aggressively, segmenting your environment, and maintaining clean, immutable backups are not glamorous. They are not AI-powered. But they address the attack anatomy that AI tools, offensive or defensive, haven’t fundamentally changed.

The Recovery Imperative

Strengthening cyber fundamentals, in practice, means one thing above all else: knowing that when something gets through, you can recover without paying a ransom.

That requires three things from your backup and recovery posture:

  1. Immutability. Backups that can’t be encrypted or deleted by ransomware, even by a compromised admin credential. This isn’t optional anymore. If your backups live in the same environment as your production data and share the same access credentials, they aren’t backups; they’re part of your blast radius. Backblaze B2 Object Lock is S3-compatible, so if your team is already running Veeam, Commvault, MSP360, or Nutanix, you’re not replacing your backup stack. You’re giving it an immutable target that ransomware can’t touch.
  2. Air-gap or off-site isolation. Object Lock, WORM storage, and geographically separate backup targets all put meaningful distance between your recovery point and an active attack. When AI tools can chain dozens of steps in a corporate network attack simulation autonomously, “isolated backups” means genuinely isolated, not just a separate folder. Version history matters here too: the ability to roll back to a known pre-attack state, not just the most recent snapshot, is what separates a clean recovery from discovering your restore point was already compromised.
  3. Recovery time that matches the threat. AI-accelerated attacks mean recovery has to be fast. A backup strategy built around 72-hour RTOs made sense in a different threat environment. In 2026, breach costs approaching $10.22 million in the US, the question your leadership should be asking is: how long does it actually take us to restore from a clean state? Cold storage tiers that require hours of retrieval before a restore can even begin are a liability when the clock is running. Backblaze B2 is hot storage: your data is available immediately after detection, with no retrieval queue to wait on.

A Practical Checklist for IT Leaders Right Now

The Claude Mythos announcement, the Fable 5 public release, and GPT-5.5’s expanded cybersecurity capabilities are a forcing function.  Not because Mythos-class capability is in attackers’ hands today, but because the direction of travel is confirmed, the timeline is compressed, and the question is no longer whether equivalent offensive tools will proliferate, only when. 

A few things worth doing before that happens:

  • Audit your backup environment’s blast radius. Can ransomware that has compromised your production environment also reach your backups? If yes, fix that first.
  • Test your recovery time. Not just that backups exist, but how long an actual restore takes from your most recent clean snapshot. If you don’t know the number, you don’t have a recovery plan. You have a filing system. Backblaze gives you 3x your stored data in free egress each month, which removes the cost barrier that causes most teams to skip DR testing entirely. Run the restore. Know the number.
  • Pressure-test your identity controls. Credential abuse and phishing remain the dominant entry vectors. MFA, compromised credential monitoring, and least-privilege access aren’t new ideas, but they’re still the fastest path to closing the doors AI-powered attacks walk through.
  • Patch faster. The Verizon 2026 DBIR found exploited vulnerabilities are now the leading breach entry point. The median time organizations take to fix a known flaw is 55 days. AI-assisted attackers don’t wait 55 days. 
  • Layer your defenses, but anchor to recovery. Perimeter protection, endpoint detection, vulnerability scanning: these all matter. But they’re all designed to catch something before it executes. Immutable backups are what you rely on when something executes anyway.
  • Revisit your RTO and RPO against today’s breach costs. The math has changed. A $10.22 million average US breach cost changes the calculus on what it’s worth spending on faster, more resilient recovery infrastructure.

The Last Thing

Anthropic made a decision that deserves credit: they looked at what Claude Mythos could do and chose not to hand it to the world on day one. Project Glasswing is a serious attempt to use the model’s capabilities on the right side of this fight, and the coordinated disclosure of thousands of vulnerabilities to the organizations responsible for patching them is meaningful defensive work. 

But the history of powerful technology is not “we invented it and kept it safe.” It’s “we invented it, others reproduced it, and everyone had to adapt.” The 6-to-12-month window for equivalent capability to reach adversarial hands isn’t fearmongering; it’s Anthropic’s own forecast. Other AI companies are building toward the same capability threshold right now, and not all of them will ship with the same safeguards. 

The organizations that come through this transition will be the ones that took recovery seriously before they needed it. Not because detection failed, but because recovery is the one safeguard that works regardless of what the attacker is running.

Backblaze B2 with Object Lock puts immutable, air-gapped backup storage within reach of organizations that can’t afford hyperscaler pricing (which, as it turns out, is most of them). Start a free trial or talk to our team about building a ransomware-resilient backup architecture before the threat landscape shifts again.

The post AI Can Now Execute 73% of Expert-Level Cyberattacks. Here’s What IT Leaders Need to Do. appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

S&P Global’s innovative disaster recovery strategy using Amazon FSx for NetApp ONTAP snapshots

Post Syndicated from Nishanth Charlakola original https://aws.amazon.com/blogs/architecture/sp-globals-innovative-disaster-recovery-strategy-using-amazon-fsx-for-netapp-ontap-snapshots/

This post is co-written by Nishanth Charlakola from S&P Global.

Organizations have a requirement to build high availability and disaster recovery (HA/DR) solutions for their complex SQL Server infrastructure to maintain data availability and integrity. With the rapid pace of cloud adoption, businesses across different industries have realized the value of a successful proof of concept (POC) for any technical project that migrates existing environments to the cloud. For companies of any size, it is important to set standards, minimize risks, and conduct business and technical validation while maintaining speed.

In this post, we explain how S&P Global Market Intelligence implemented an innovative disaster recovery solution for their Capital IQ platform using Amazon FSx for NetApp ONTAP. This solution enables immediate failover to read-only mode in a secondary region within 15 minutes, followed by full read-write recovery when needed. This approach achieves reduction in failover time while maintaining data consistency for global financial operations.

S&P Global Market Intelligence has been providing essential intelligence that unlocks opportunity, fosters growth, and accelerates progress for more than 160 years. The company offers Environmental, Social, and Governance (ESG) solutions, deep data, and insights on critical economic, market, and business factors.

Business challenge

S&P Global Market Intelligence must maintain uninterrupted access to information, even during regional outages. The Capital IQ platform supports global clients who rely on timely and accurate data for decision-making, with business requirements mandating strict Recovery Time Objectives (RTO) and Recovery Point Objectives (RPO).The primary business challenge was making sure that once the decision to fail over has been made, the DR read-only system becomes operational and accessible within 15 minutes. This rapid failover window makes sure you can continue accessing essential financial information with minimal disruption during failover events.

Key challenges addressed

  • Facilitating sub-15-minute access to critical financial data during regional service disruptions
  • Maintaining data consistency for financial reporting
  • Supporting system availability during production code releases
  • Optimizing cross-region data replication costs without compromising performance
  • Meeting regulatory requirements for business continuity in financial services

Solution overview

S&P Global’s DR strategy for the Capital IQ platform follows a two-pronged approach that balances immediate availability with complete recovery capabilities:

  1. Immediate failover to DR in read-only mode – using ONTAP snapshots and FlexClone technology for sub-15-minute recovery
  2. Conversion of DR system from read-only to read-write mode – following established geo-cluster design with SnapMirror replication

This approach helps you continue accessing essential financial data during disaster scenarios, even while the full recovery process is underway, facilitating business continuity without compromising data integrity.

Prerequisites

To implement this solution, you need the following:

Security and encryption

Amazon FSx for NetApp ONTAP supports encryption of data at rest and in transit, helping you meet security and compliance requirements. Data at rest is encrypted using AWS Key Management Service (AWS KMS) keys, and data in transit can be encrypted using SMB Kerberos encryption or NFS Kerberos. For SnapMirror replication, data transferred between file systems is encrypted in transit using AES-256-GCM encryption. For more information about security capabilities, see Security in Amazon FSx for NetApp ONTAP.

Architecture components

The solution architecture includes four key layers:

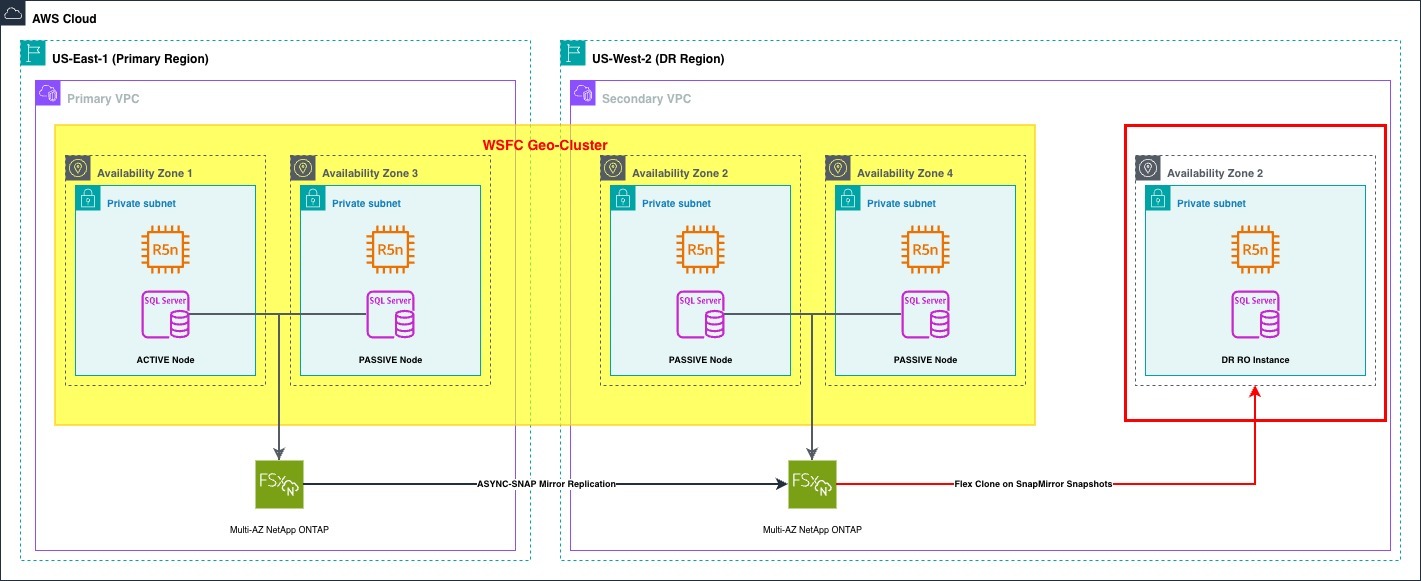
  • Compute layer: A four-node geo-distributed Windows Server Failover Cluster (WSFC) spanning two AWS Regions
  • Storage layer: Two Amazon FSx for NetApp ONTAP file systems, one in the primary region (US-East-1) and another in the DR region (US-West-2)
  • Data replication: SnapMirror replication from US-East-1 to US-West-2 with 15-minute intervals
  • Rapid recovery: FlexClone volumes created from existing SnapMirror snapshots in the DR region

AWS multi-region SQL Server high availability and disaster recovery architecture with WSFC Geo-Cluster spanning US-East-1 and US-West-2, using Amazon FSx for NetApp ONTAP with SnapMirror replication.

Figure 1. Cross-region disaster recovery architecture using Amazon FSx for NetApp ONTAP with SnapMirror replication and FlexClone-based rapid recovery.

Technical implementation

Cross-Region data replication

The Capital IQ team established SnapMirror replication between their production Amazon FSx for NetApp ONTAP file system in US-East-1 (N. Virginia) and their DR file system in US-West-2 (Oregon), making sure the DR region maintains a consistent copy of production data.The SnapMirror replication is configured with a 15-minute schedule between primary and DR Amazon FSx for NetApp ONTAP file systems. This frequent replication makes sure the DR region stays closely synchronized with production, minimizing potential data loss during failover events. The actual Recovery Point Objective (RPO) varies based on production environment activity. During lower activity periods, the RPO can be just a few minutes, while higher transaction volumes may result in a slightly increased RPO within the 15-minute window.

Using FlexClone for rapid recovery

A key element of S&P Global’s disaster recovery strategy is the use of NetApp FlexClone technology in conjunction with SnapMirror snapshots. A scheduled automation process refreshes the DR environment daily by identifying the most recent SnapMirror snapshot available in the DR region and creating a FlexClone volume from that point-in-time image. With this read-only DR instance pre-provisioned in advance, initiating failover is primarily an application cutover step — redirecting traffic to the ready instance in the DR region.This approach is highly efficient and non-intrusive. By using snapshots for FlexClone creation, the solution maintains the integrity of ongoing SnapMirror replication between production and DR environments. The FlexClone volume operates independently of the active SnapMirror relationship, meaning it does not interrupt or interfere with data replication processes. This separation allows continuous data protection and synchronization, even while the DR environment serves live read-only traffic.

FlexClone creation process

  1. Identify the latest SnapMirror snapshot in the DR region
  2. Create a FlexClone volume from this snapshot using the NetApp ONTAP CLI:

Note: The following example demonstrates a typical FlexClone creation command. Actual parameters should be adjusted for your environment.

volume clone create \-vserver dr-svm \-flexclone ciq_data_readonly \-parent-volume ciq_data_mirror \-parent-snapshot snapmirror.latest \-type RW

  1. Present the FlexClone volume and its LUNs to the read-only SQL Server instance in the DR region
  2. Direct application traffic to the read-only instance

Key advantages

  • Sub-15-minute recovery: FlexClone creation completes in under 2 minutes
  • Storage efficiency: FlexClones consume minimal additional storage as they share data blocks with the parent volume
  • Data consistency: The clone represents a point-in-time snapshot of production data
  • Operational isolation: The clone operates independently from ongoing SnapMirror replication

Full read-write recovery process

While read-only recovery provides immediate business continuity, transitioning to full read-write capability in the DR region follows these orchestrated steps:

  1. Stop SQL Server and freeze writes in the primary region
  2. Apply the final SnapMirror update to the DR region
  3. Break the SnapMirror relationship to make the DR volume read-write
  4. Reverse the replication direction (DR to primary)
  5. Fail over SQL Server resources to the DR nodes
  6. Resume normal operations in the DR region

Business benefits

This approach to disaster recovery has delivered significant benefits:

  • Enhanced business resilience: The solution maintained established RTO and RPO standards while transitioning to cloud infrastructure, successfully extending proven on-premises DR capabilities to the cloud.
  • Continuous access during outages: Clients experience minimal disruption during regional disaster scenarios. The pre-provisioned read-only instance means failover is a redirect, not a rebuild.
  • Resilience beyond disasters: Read-only instances also support application availability during production code releases extending the solution’s value beyond its original DR scope.
  • Lower infrastructure costs: FlexClone technology’s efficient data block sharing minimizes storage overhead in the DR region, reducing costs while maintaining comprehensive data protection.
  • Cloud-native without compromise: By moving from on-premises infrastructure to Amazon FSx for NetApp ONTAP, S&P Global gained cloud agility and elasticity while preserving the mature data management capabilities that financial services operations require.
  • Regulatory compliance: The solution meets stringent financial services requirements for business continuity and data availability.

Conclusion

S&P Global Market Intelligence’s implementation demonstrates that organizations can achieve both rapid disaster recovery and cost efficiency using Amazon FSx for NetApp ONTAP. By combining SnapMirror replication with FlexClone technology, they built a DR strategy that is faster, leaner, and more flexible than its on-premises predecessor while maintaining the reliability standards that 160 years of client trust demand.For financial services organizations navigating similar migrations, this approach offers a proven blueprint: replicate what works, modernize how it runs, and maintain the same level of data protection clients expect.

“Adopting Amazon FSx for NetApp ONTAP has helped us extend our proven disaster recovery strategy into the cloud. The ability to use native ONTAP snapshots and FlexClone technology on AWS enables us to deliver the same level of data protection and business continuity that our clients expect, without compromise. This solution bridges the gap between on-premises reliability and cloud agility.”

— Nishanth Charlakola, Director, S&P Global Market Intelligence

If you need guidance on implementing Amazon FSx for NetApp ONTAP or architecting disaster recovery solutions for financial services, contact your AWS account team.


About the authors 


2026-06-07 числа за IT-то

Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3528

Още малко числа, след първите и вторите, пак идващи от НСИ.

От миналата година (влизащ в действие от тая) има НКИД-2025, “Национална класификация на икономическите дейности” (или само класификация, среща се и без “Н”), в която разделиха предишната категория “СЪЗДАВАНЕ И РАЗПРОСТРАНЕНИЕ НА ИНФОРМАЦИЯ И ТВОРЧЕСКИ ПРОДУКТИ; ДАЛЕКОСЪОБЩЕНИЯ” на две нови – “ИЗДАТЕЛСКА И РАДИО- И ТЕЛЕВИЗИОННА ДЕЙНОСТ, СЪЗДАВАНЕ НА СЪДЪРЖАНИЕ И ДЕЙНОСТИ ПО РАЗПРОСТРАНЕНИЕ” и “ТЕЛЕКОМУНИКАЦИИ, КОМПЮТЪРНО ПРОГРАМИРАНЕ, КОНСУЛТАНСКИ ДЕЙНОСТИ, ИНФРАСТРУКТУРА ЗА ИНФОРМАЦИОННИ ТЕХНОЛОГИИ И ДРУГИ ИНФОРМАЦИОННИ УСЛУГИ”. Вече има данни в Демографска и социална статистика – Пазар на труда – Наблюдение на работната сила – Заети лица и коефициенти на заетост – национално ниво; статистически райони; области, в които може да се види, че за първото тримесечие има 110.3 хиляди човека заети в нашата област.

Все още няма по тази разбивка данни за заплатите и другите такива интересни неща, надявам се да се появят.

Тия дни ще си поискам данните за договорите, току-виж там има още нещо интересно.

Woodruff: You shouldn’t trust trusted publishing

Post Syndicated from jzb original https://lwn.net/Articles/1081690/

William Woodruff, better known online as “yossarian”, has published
a blog post to make the case that users should not place their trust
in trusted
publishing
:

Trusted Publishing is a mechanism for establishing trust between an
external machine identity (like a CI/CD workflow) and one or more
projects on a package index/registry. The “trust” in “Trusted
Publishing” refers to that trust relationship, and not to anything
else.

It is not, and cannot be, a signal for package trust or
quality. You cannot use it to determine whether a package is safe or
“good,” and PyPI consciously stymies attempts to misuse it for that
purpose by not rendering it as a “green checkmark” or anything else of
the sort.

Or as another framing: Trusted Publishing is just a form of
authentication. It doesn’t tell you anything other than that an upload
was authenticated, which all uploads to PyPI are.

LWN covered trusted
publishing in June.

Joy in learning computer science with Experience CS

Post Syndicated from Liz Walsh original https://www.raspberrypi.org/blog/joy-in-learning-computer-science-with-experience-cs/

Last fall I met with Mark Nechanicky and Taryn Israel Nechanicky, two teachers from Albert Lea, Minnesota. Mark and Taryn are bringing computer science into their classroom with Experience CS, our free cross-curricular resource teaching computer science concepts and reinforcing students’ content knowledge in areas including math, science, language arts, and more.

We talked about some of the challenges they faced, and how they’ve worked around them, including constraints on their time and the requirements around teaching their core content areas. But most of our conversation was on the impact the Experience CS resources had on their students. Mark and Taryn shared how teaching cross-curricular computing helped their students to find joy in their learning, express creativity in their projects, and build a sense of leadership within the classroom.

A young person and a teacher looking at a laptop in a classroom setting.

In a little under a week Mark, Taryn, and I will be presenting a breakout session titled Foster Student Engagement, Confidence, and Collaboration through Integrated CS in New Orleans, Louisiana at the Computer Science Teachers Association (CSTA) annual conference. You can read more about our session at the end of this blog post. For now, here’s a preview.

Joy in learning through student agency

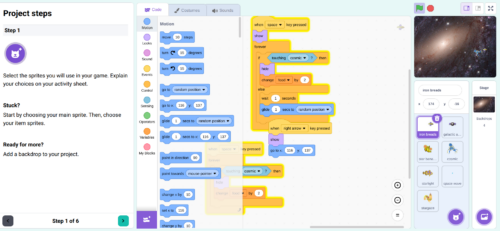
When it was time to code, Taryn’s students cheered. She said, “I believe this is because the curriculum makes coding feel like play, which is the basis of how Scratch is designed. Students have choices, agency, chances to make mistakes, and problem-solve individually and together.”

Taryn shared an example of student agency she saw when teaching the first lesson in Weather watchers, a unit designed for students in third grade (ages 8–9) that integrates math and science concepts with programming. During that lesson a student was able to bring her beloved dog, Chewy, into her program as a sprite, and create something meaningful to her.

Fostering creativity among students

While we were designing the units of Experience CS, we focused on ensuring that our resources provided students and teachers with properly scaffolded learning experiences. We did this to support all students in their computing journey, and to provide them with the opportunity to be creative and express themselves in their programs.

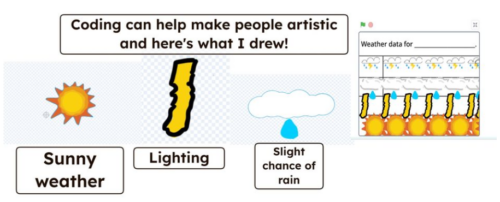
In the Weather watchers unit, students collect weather data and create picture graphs using sprites that represent different weather conditions. Mark’s class let us know the starter project for the unit was missing something — keep an eye out for a tornado sprite in the future! With a little creativity and problem solving, they were able to design just the sprite they needed.

Mark added, “students aren’t just following step-by-step directions to create identical projects. As they work through the lessons, they have the flexibility to add their own sprites, design additional interactions, customize characters, and extend projects in ways that reflect their interests.”

A screenshot from a Scratch programming project.
A student explains how they created their own sprites for a project in Weather watchers.

Fostering leadership in the computer science classroom

The largest part of our discussion was how teaching cross-curricular computer science created environments for all students to become leaders. “One thing I’ve noticed is that coding creates leadership opportunities for students who don’t always get the chance to be seen as the expert. Because it is a new experience for almost everyone, it changes the dynamic in the classroom. Students with Individualized Education Plans (IEPs), English Language Learners, introverted students, and students who may struggle in other academic areas are often the ones discovering new ideas, solving problems, and showing classmates how to do something cool.”

Mark also shared an experience he had while teaching Digit dash, a game design unit that reinforces multiplication fluency, designed for students in fourth grade (ages 9–10). That unit was the first time his students had explored how variables can be used to store a score in a game. The first student to figure out how to use variables in their program was introverted, but became the class “expert” on variables and modeled it for his fellow students.

A screenshot from a Scratch programming project.
Sample student final program from Digit Dash in Code Classroom.

Find us at CSTA

If you’re heading to New Orleans, we hope to see you at our CSTA breakout session, Foster Student Engagement, Confidence, and Collaboration through Integrated CS. During our session, you will be able to hear directly from Mark and Taryn on the impact that teaching Experience CS has had on their students in the last school year. We will include examples from the Experience CS units Weather watchers, Logic and lore, Picture this!, and Digit dash.

Our CSTA session will take place on July 17th, from 3:00 PM to 4:00 PM CT, in Borgne (Floor 3).

And we’d love to hear from you. Have you used our Experience CS resources in your classroom? How did it go?

The post Joy in learning computer science with Experience CS appeared first on Raspberry Pi Foundation.

[$] Faster RCUs and lockless memory allocation

Post Syndicated from daroc original https://lwn.net/Articles/1081009/

Puranjay Mohan shared some of the

work
he’s been doing recently on improving the
performance of read-copy-update (RCU) at the 2026

Linux
Storage, Filesystem, Memory-Management, and BPF Summit
; his talk would have
been nice context to have earlier in the day when Harry Yoo and Alexei
Starovoitov led a session about the

new kmalloc_nolock() function
that
allows for lockless allocation from any kernel context, and which interacts with
the RCU subsystem to allow that. This article therefore covers the two sessions
together and in the reverse order, to provide that missing context.

Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1081644/

Security updates have been issued by AlmaLinux (nodejs22 and nodejs24), Fedora (clamav, hplip, kernel, kernel-headers, librabbitmq, mingw-expat, mir, perl-Imager, podman-tui, prometheus-podman-exporter, python-rpds-py, rust-ashpd, rust-busd, rust-gtk4-macros, rust-inferno, rust-quick-xml, rust-reqsign-aws-v4, rust-wayland-scanner, and sandogasa), Oracle (container-tools:rhel8, kernel, mariadb:10.11, mariadb:11.8, nginx, perl:5.32, php, php:7.4, rrdtool, ruby:2.5, ruby:3.3, ruby:4.0, and uek-kernel), Red Hat (kernel, opentelemetry-collector, and python-urllib3), Slackware (c-ares and openssh), SUSE (bind, chromedriver, cryptsetup, s390-tools, dnsmasq, jackson-annotations, jackson-core, jackson-databind, lcms2, pacemaker, perl-Cpanel-JSON-XS, perl-Crypt-SaltedHash, postfix, and python-mistune), and Ubuntu (gnutls28, gzip, openssh, php7.0, python-parsl, python3.10, python3.12, python3.14, request-tracker5, socat, sogo, and tar).

IBM Expands z17 and LinuxONE 5 Mainframe Lineups With Single Frame and Rackmount Servers

Post Syndicated from Ryan Smith original https://www.servethehome.com/ibm-expands-z17-and-linuxone-5-mainframe-lineups-with-single-frame-and-rackmount-servers/

IBM is expanding its mainframe lineups with new single-frame and rackmount z17 and LinuxONE 5 offerings for smaller customers. As well, the company is releasing an 18U LinuxONE box for new customers called the LinuxONE Express

The post IBM Expands z17 and LinuxONE 5 Mainframe Lineups With Single Frame and Rackmount Servers appeared first on ServeTheHome.

Cloudflare proudly joins the UK government’s Cyber Resilience Pledge

Post Syndicated from Katie Visser original https://blog.cloudflare.com/cloudflare-joins-uk-cyber-resilience-pledge/

Today, the UK government launched the Cyber Resilience Pledge: a voluntary framework inviting organizations to commit to foundational cybersecurity governance, board-level accountability, and comprehensive cybersecurity coverage across supply chains. Cloudflare is proud to join the pledge’s founding cohort of signatories and continue our long-standing work with the Department of Science, Innovation and Technology (DSIT), National Cyber Security Centre, and others to shape a more secure, future-ready digital economy for the UK.

The pledge’s core pillars — democratizing security, leadership accountability, and radical transparency — have been at the heart of Cloudflare since day one. Instead of approaching this framework as a new set of commitments to meet, we see it as a welcome validation from the UK government of the security philosophy and principles Cloudflare has championed for over a decade. We are glad to see the rest of the industry moving in this direction.

This pledge is an important step, and it comes at a time of significant cyber risk. In the first quarter of 2026, Cloudflare’s global network blocked an average of 234 billion cyber threats every day. Recently, we mitigated a hyper-volumetric DDoS attack that peaked at 31.4 Tbps. At the end of 2025, Cloudflare data showed that the UK had risen to be the sixth-most targeted location across the globe for DDoS attacks, with threat actors increasingly targeting application-layer services in financial services, aviation, and regional government infrastructure. This trend is consistent with broader data from the UK Cyber Security Breaches Survey, which revealed that 43% of surveyed British businesses and 28% of charities reported suffering from a cyber incident this past year.

At the same time, frontier AI models are rapidly changing the security landscape, lowering the barrier to entry for attackers, and enabling more automated vulnerability scanning and more convincing phishing campaigns. Cloudflare has long been preparing for this shift. The defensive architecture we recently published for frontier cyber models reflects the same principle: security has to evolve as quickly as the threats companies face. Every layer of that harness architecture, from ML-based attack scoring to Zero Trust access controls, is available to Cloudflare customers today.

Against that backdrop, the pledge does something essential: it recognizes that collective defense is critical. It asks organizations to make cyber resilience a leadership-level priority, to implement appropriate controls to boost threat awareness, and to help ensure supply chains meet a meaningful security baseline. Most breaches still exploit well-understood gaps, like unpatched systems, weak access controls, or poor vendor oversight. Encouraging more organizations to close those gaps through enhanced governance, monitoring, and implementation is a necessary starting point. 

Cloudflare is fully aligned with the UK government’s mission to elevate cybersecurity governance within companies and organizations of all sizes. Every organization that raises its baseline makes the Internet safer for everyone else. Our mission at Cloudflare is to help build a better Internet, and we have always believed that cybersecurity and resilience work best when they are universal. A more resilient Internet is a better Internet. 

Why resilience matters

Cyber resilience is increasingly recognized as a core business requirement. Customers expect services to be available at all times, responsive, and trustworthy. And that’s true even when the environment gets more challenging to operate in, whether from increased attacks, outages, abuse, or complexity. 

Resilience ultimately is not just about recovering after something goes wrong. It is about designing security systems and operating models that can proactively track threat signals, seamlessly absorb disruptions, and adapt to be better. In this way, security and resilience are inseparable. Security controls are what make resilience real. 

How Cloudflare helps strengthen resilience through security

Thanks to the scale of our network, we can help organizations build resilience by shifting protection closer to the edge, before threats reach core systems. We think about cyber resilience through a few core architectural principles:

Security as a default, not a product tier

Cloudflare believes baseline security protections should be available to all and has been living that principle since our founding. We were the first to offer SSL certificates, required for traffic encryption, to all users. We protect vulnerable voices through our Impact programs like Project Galileo and the Athenian Project. We continuously push the boundaries of Internet cryptography, including the deployment of post-quantum cryptography across our network. Our free plan includes unmetered DDoS protection regardless of the size, duration, or volume of attacks, and also provides access to a global content delivery network (CDN) and DNSSEC. These capabilities have historically required expensive hardware and specialist security teams. But the pledge’s aim of elevating organizational resilience and raising the cyber resilience floor across the UK economy only works if small businesses, local authorities, public services, and startups can afford to participate. Our model directly supports that goal.

The network is the sensor

Because Cloudflare directly peers with more than 13,000 networks globally, we see attack patterns as they emerge. Threat intelligence collected in one part of the network can be turned into protection everywhere else in a matter of seconds. A threat detected while mitigating an attack on a customer in Singapore can become a rule that helps protect a customer in Sheffield moments later. That same visibility also helps improve how we detect, score, and respond to attacks across Cloudflare’s network and security services. Visibility at scale leads to resilience at scale for Cloudflare’s customers and network.

Cloudflare is customer zero

Our customers benefit from the exact same industry-leading security products and infrastructure that safeguard our own systems. Cloudflare employees use Cloudflare Access and Gateway to reach internal applications, and every request to an internal system requires hard key-based multi-factor authentication, posture checks, and cryptographically verified identity tokens. We test every security layer on ourselves first, and use our own internal learnings to build better security solutions for ourselves and our network. By integrating security into every level of the business, Cloudflare demonstrates a ground-up commitment that sits at the very heart of the pledge.

Transparency and response

Finally, resilience requires honesty and transparency when things go wrong and a commitment to strengthen systems for the future. When security incidents or zero-day vulnerabilities emerge, we publish deep-dive technical postmortems on the Cloudflare Blog. We share indicators of compromise and architectural retrospectives, so the broader security community can learn from our telemetry. But transparency is only the first step. We treat every incident as a mandate to make our network more resilient. After a significant outage last fall, our Code Orange effort mobilized engineering teams to rebuild for resilience. They designed systems to “fail small,” and built new tooling to enforce safer configuration changes and automate best practices, so the same failure can’t happen twice.

How Cloudflare implements the Cyber Resilience Pledge commitments

As noted above, today’s voluntary pledge asks companies and organizations to commit to certain standards in board responsibility and governance, supply chain security, and the technical requirements under the UK’s Cyber Essentials certification scheme. As a global cybersecurity and network resilience provider, we operate an advanced internal cybersecurity governance model. 

Board responsibility and governance

With cybersecurity and resilience at the core of Cloudflare’s global business, we are proud to be a leader in developing and advocating for practices that strengthen cybersecurity at the board level.

Our Board of Directors treats cyber risk oversight as a core responsibility. Cloudflare’s Board receives cybersecurity briefings from our Chief Security Officer on at least a quarterly basis, including direct threat briefings. In addition, the Audit Committee of the Board receives quarterly briefings on enterprise risk management that include a specific focus on cyber risks and the company’s process for regularly reviewing and mitigating cyber threats and risks.

We are grateful that DSIT’s toolkit and resources are available to benchmark, reinforce, and support boards’ ongoing governance efforts across the entire UK economy.

Supply chain security and Cyber Essentials (CE)

Cloudflare adheres to rigorous international security compliance certifications. We require our supply chain to meet comprehensive international standards that incorporate and build upon the core requirements of Cyber Essentials. Cloudflare manages vendor risk globally, prioritizing comprehensive international security frameworks that encompass and exceed the fundamental technical controls of the Cyber Essentials program.

More specifically, Cloudflare requires critical suppliers to adhere to rigorous, internationally recognized security compliance certifications and reports — primarily ISO 27001 and SOC 2 Type II. These frameworks explicitly require the implementation of firewalls, secure configurations, user access controls, malware protection, and patch management (the five core pillars of Cyber Essentials).

Cloudflare will continue to use a risk-based methodology to evaluate suppliers. We commend DSIT for expanding access to the Cyber Essentials Supplier Check Tool, which Cloudflare can adopt for localized supply chain validation within the UK. And for global suppliers where UK Cyber Essentials is not a native or practical certification, Cloudflare will accept equivalent international certifications (like ISO 27001) as sufficient verification of a robust security posture. These practices help ensure that Cloudflare’s critical supply chain undergoes stringent security vetting, meeting the risk-reduction outcomes intended by Cyber Essentials.

Onward

Cyber resilience is not a one-time pledge — it is a continuous practice of building systems that fail safely, recover quickly, and learn to be better. For organizations across the UK, it means making cybersecurity a business-critical priority, with leadership buy-in, teams that understand the threats they face, and supply chains managed for risk. The pledge sets a baseline that every organization should strive to meet.

Cloudflare built its platform on the belief that security and resilience should be universal and available to both the smallest developer and the largest enterprise. We are proud to stand with DSIT and the other signatories of this pledge, and look forward to continued partnership and innovation to elevate cyber resilience across the UK and around the globe.

Рене Карабаш: Да обичаш означава да…

Post Syndicated from Роси Михова original https://www.toest.bg/rene-karabash-da-obichash-oznachava-da/

Въпросите задават Пабло Неруда и Роси Михова

Рене Карабаш: Да обичаш означава да...

Пабло Неруда умира на 23 септември 1973 г. в чилийската столица Сантяго – дванайсет дни след военния преврат на Аугусто Пиночет. Само ден по-рано поетът, който е виден комунист и приятел на сваления президент Салвадор Алиенде, планира да замине в изгнание в Мексико. Това обаче така и не става. След внезапната смърт на Неруда на бюрото му са открити осем ръкописа. Един от тях е озаглавен „Книга на въпросите“.

„Книга на въпросите“ (Libro de las Preguntas) е нещо като лексикон в стихове. Той включва 316 кратки поетични въпроса, оформени като 74 отделни стихотворения. Неруда вярва, че светът е пълен с „невидими отговори“ и работата на човека е да се научи да задава правилните въпроси. А неговите са едновременно фантасмагорични, съзерцателни, предизвикателни, понякога дори и пиперливи – нещо като горещи, току-що извадени от фурната емпанади с плънка от сюрреализъм, детско удивление пред света и мрачна метафизика.

Оттук тръгва и нашият разговор с моята събеседничка, която аз срещам за първи път, но в ума си вече съм решила, че е сродна на Неруда душа. Това е писателката, поетеса и сценаристка Рене Карабаш*.

Предлагам за загрявка да започнем с една поредица от блицвъпроси. Защо облаците са толкова тъжни, когато спрат да плачат? 

Защото няма кой да полива градината им.

На кого се усмихва оризът, когато показва белите си зъби? 

На печеното пиле, разбира се.

Ако всички реки са сладки, откъде морето взема солта си? 

От сълзите, изплакани от близките на всички удавници.
А също от сълзите на рибите.

Какво мислят рубините, когато видят сок от нар? 

Че са на брега на Червено море.

На какво се смее динята, докато я разсичаме до смърт? 

На ножа. И на този, който го държи. Динята знае: и твоето време ще дойде.

Кое е това, което дървото чува от земята и го казва на небето? 

Нещо, което мисля, че трябва да остане в тайна.

Какво прошепва пепелта на огъня, който гори наблизо? 

Чакам те.

Защо дърветата крият великолепието на своите корени? 

Защото всеки трябва да крие и пази това, което му е най-ценно.

А може би защото никой не обича да го гледат, когато се храни… Дали розата е гола, или това е нейната рокля?

Розата е облечена със своята голота. И с парфюма си. Тя държи на него, защото иначе пчелите няма да ѝ обръщат внимание. Орхидеята обаче е друго нещо. Нейната красота е толкова поразителна, че тя няма нужда от аромат, за да привлича. Има и такива хора.

Къде отиват птиците, когато умират? Има ли гробище за крила?

Когато удари часът, птиците се връщат, за да умрат близо до гнездото си.

А в „Остайница“ пишете, че гробището за крила е домът. Защото точно там някой ги прерязва.

За да разбереш точно колко ти е важно да летиш.

Защо тялото ми продължава да ме носи, когато душата ми е изпаднала някъде?

Душата и тялото са близнаци. И когато единият няма сила да продължи, другият го носи на гръб.

Защо димът винаги се опитва да влезе в небето? 

Защото прилича на нас, хората. Накрая ние също тръгваме по вертикалата натам, нали? Поне това е оптимистичната версия.

А може би споделя нашето атавистично желание да оставим диря?

Да препикаем този свят? Да, чудя се откъде идва това наше желание. Дали маркираме територии? Или се прицелваме в безсмъртието? Аз все пак вярвам, че най-непреходното, което остава след нас, е любовта, която сме дали на другите. И си мисля за моята баба, която ми е дала най-чистата обич и с която дори днес продължавам да си говоря по разни начини. Един ден ще разкажа за нея на моите деца и тя ще е още жива – дори когато мен вече няма да ме има.

Къде се губи времето, което сме пропуснали? 

Вероятно в стаята, където се трупат всички пропуснати неща и моменти. Като онази магическа стая в книгите за Хари Потър, в която можеш да намериш всичко, което търсиш, когато имаш отчаяна нужда от него. Там оставяме пропуснатото време, за да можем да си го потърсим отново при първа възможност.

Но аз също така вярвам, че нещата, с които смятаме, че сме се разминали в този живот, всъщност се случват в някаква паралелна реалност. Не само хубавите и добрите неща, но и нашите грешки, болки или унаследени травми, които продължаваме да рециклираме.

Оттук следва, че всъщност ние можем да бъдем това, което пожелаем, и да имаме това, което искаме. Но то е въпрос на вибрация. Ако човек се настрои на тази честота, че тези неща вече някъде ги има, че те вече са се случили в някакво друго измерение, то те наистина се появяват и в живота, който живеем тук и сега. Всъщност аз така разбирам пътуването в пространството и времето.

Това се вписва в моето далеч по-прагматично убеждение, че човек невинаги има живота, който би искал да има, но това не означава, че не може да бъде човекът, който би искал да бъде. Във Вашата интерпретация това наше паралелно аз съществува някъде и е въпрос на усилие и мотивация да затрептим на една честота с него.

Карл Густав Юнг има тази концепция за противоположностите, които живеят в нас. Едва когато те се срещнат и слеят, се случва онова, което можем да определим като алхимичен брак, а той конкретно нарича „индивидуация“. В живота аз си го обяснявам далеч по-просто. Например когато съм парализирана от страх, вярвам, че противоположното е също в мен – че смелостта е в мен. Нужно е само да стигна до нея, да я проявя с надигащия се в мен ужас и така да стана цяла. Именно тази моя цялост ми дава усещане за сила. Защото страхът вече не изпълва всичко в мен. Защото в неговата стая живее и куражът ми.

Защо ни хапят бълхите и литературните критици?

Защото си нямат друга работа.

Аз обаче имам друг отговор във Вашия случай. Според мен Ви хапят, защото Ви жалят и не искат да Ви унищожат с мълчанието си. Човек, особено ако е творец, най-лесно се „убива“ с безразличие. Но същото важи и за бесовете, ако вярваме на едно Ваше стихотворение:

Още колко стиха трябва да напиша, за да укротя бесовете си?
Спри да пишеш…
бесовете умират сами…
от бялото на листа.

Така е. Но ще споделя тъжната истина, че професионалната литературна критика навсякъде вече е не просто застрашен, а изчезващ вид. Социалните мрежи, инфлуенсърите, хората, които коментират само по заглавие, без да са чели текста, замениха задълбочения литературен анализ. Мисля, че ако литературната критика иска да продължи да живее, тя трябва да се адаптира към новата дигитална реалност, към новия свят, който не ни пита дали искаме, или не да останем аналогови. За жалост.

Неруда има и такъв брутален въпрос: на какъв принудителен труд е осъден Хитлер в ада?

Може би в някакъв следващ живот да има дете, което на игра да си смени дрехите с някое еврейско момченце в нацистка Германия. Вие довършете историята.

Тук ще се изкуша да цитирам отговора на самия Неруда в превод на Никола Инджов:

„На какъв принудителен труд е
оставен Хитлер в ада?
Трупове и стени ли вапсва,
газ пагубен ли опитва?
Дават ли му да яде пепел
от деца, изгорени живи?
Или го насилват да пие
човешка кръв от фуния?
Или му набиват в ченето
изтръгнати златни зъби?

Или му правят постеля
от концлагерна тел бодлива?
Или кожата му татуират
за абажури на лампи в пъкъла?
Или му късат месата
на огъня черните псета?
Или денонощно е длъжен
да стои между своите жертви?
Да умира, без да умира,
вечно под газа отровен?

Да, брутално е наистина. Но да не забравяме, че Хитлер е личност, която ни се е случила наистина. Той не е злодей от хорър фентъзи. Проблемът е, че днес също има хитлеровци, престорени на Спасители. И човек трябва все повече да напряга критическата си мисъл и да подсилва емпатията си, за да може да ги разпознава.

Вярно ли е, че в мравуняка мечтите са задължение? 

Да, вярно е. Защото който не мечтае в мравуняка, бива изхвърлен от него. За да просперира едно общество, всеобщият труд не е достатъчен. Нужна е и мечта. Мечтата на мравката е да занесе едно листо оттук дотам. Нашите мечти не са по-различни. Те на практика се свеждат до същото – дават ни посока и цел, а с тях – и илюзията за смисъл. Или самия смисъл?

Тогава трябва ли мечтите да са изпълними?

Някои трябва да си останат мечти. Особено ако изпуснеш момента. Защото понякога мечтаем толкова дълго и упорито, че не забелязваме как се променяме. И когато мечтата ни най-после се сбъдне, ние вече сме други и тя е била мечта на някой друг човек в нас. Освен това често мечтаенето е по-хубаво от сбъдването.

Това го има и в книгата ми „Писма на Омар до бъдещата му съпруга“. В едно от писмата, които пише до своята любима, той обяснява колко му харесва това, че още не я познава. И че още може да мечтае за нея, да я идеализира, да си я представя. Защото когато се срещнат, всичко това ще свърши.

Тогава не е ли по-добре „никога“, отколкото „късно“, пита Неруда.

За някои неща е по-добре никога, други е добре да се случат, макар и късно. А има и такива, които задължително трябва да се случат късно.

Аз обаче имам татуировка на гръбнака, която гласи: „Защити ме от това, което искам“. Защото невинаги това, което искаме и чакаме, е най-доброто за нас.

И как тогава човек прави разлика между това, което не е добро и не е нужно да чака, и това, което си заслужава цялото търпение на света?

Мисля, че един от компасите е интуицията – когато усещаш, че това е твоят път и трябва да вървиш упорито по него, колкото дълъг и труден да е той. Другото е любовта към теб самия. Ако се обичаш, ако си достатъчно грижлив към себе си и имаш инстинкт за самосъхранение, тогава не би скочил в пропастта. А твоята пропаст може да бъде всичко – човек, който се държи зле с теб, или работа, от която ще прегориш, или място, което ще изцеди радостта от живота ти. С други думи, когато обичаш себе си, ще се опазиш и ще направиш правилния избор между „никога“ и „по-късно“.

При това положение кой е по-тъжен – този, който чака напразно, или този, който никога не е чакал никого? 

Този, който не познава лудостта на очакването. Клишето, че е по-добре някой да разбие сърцето ти, отколкото никой никога да не го докосне, е вярно. Страданието е за предпочитане пред апатията. Едното е животът, другото – не. (И тук не говоря от гледната точка на творец мазохист. Ако прочетете „Жажда“ на Амели Нотомб, ще ме разберете.)

Животът е като линията на сърцето – трябва винаги да има тези скокове нагоре и надолу. Ако в един момент тя стане равна, значи сме мъртви.

А докато сме живи, кое е по-трудно – да сеем или да жънем, да пускаме семена или да прибираме реколтата?

Да жънеш, да прибираш плодовете е по-тежко за мен. Защото няма по-велико нещо от това да засаждаш. И не непременно метафорично, а съвсем буквално. Това е по-леката работа на полето. Прибирането на реколтата, обработката ѝ, почистването на земята, така че да е готова за следващия сезон, е в пъти по-тежък труд.

Нека поспорим малко. Да сееш изобщо не е толкова лесна работа. Тя изисква да се изправиш пред несигурността на бъдещето и пред собствената си уязвимост. Нужно е и безразсъдство, за да започнеш от нищото и да се хвърлиш напред с надеждата, че плодът на твоя труд няма да бъде покосен от градушка, от човешки крак или човешки думи. Жътвата понякога е занаят, понякога – сблъсък с реалността. Но сеитбата е почти религиозна вяра. Тя е оптимизъм на ръба на разумното.

Това съвсем точно отговаря на една реплика, която чух днес – Have some fucking confidence in what you’re doing. И веднага я свързвам с работата си върху следващия ми роман – моята следваща сеитба. Защото много неща за тази книга още не са ми ясни, но вярвам, че в процеса на работа те ще ми се изяснят. Така че човек трябва да се довери на процеса, той да го води… и отговорите ще покълнат и изникнат сами.

А този процес, това, което се случва и в което живеем, то какво е – непрекъснат разпад или битка?

Има нещо, което често ми се налага да казвам сама на себе си: Now, you do not need to survive. Сега не се налага да оцеляваш. Може би защото е трябвало много да оцеляваме в детството си, ние имаме една травматична нагласа. Мозъкът ни постоянно е настроен на тази вълна, че трябва да се справим, трябва да се борим, трябва да оцелеем. Понякога обаче това не е нужно. Понякога можем просто да сме тук и сега и да живеем. И да скачаме във всяка битка.

От друга страна, разпадът е чудесно нещо. Той е краят, който поставя ново начало. Шива е върховният бог на разрушението, но и част от съзиданието на битието. Той танцува своя танц върху земята и когато тя се разпада под нозете му, остава най-малкото зрънце на любовта. И от тази молекула всичко тръгва и се разлиства наново. Така че разпадът е другото лице на сътворението.

Пък и какво значи разпад? То всичко е енергия – събира се, разделя се, размества се, намества се.

Добре, като за финал: дали се научаваме да бъдем състрадателни, или само слагаме маската на състрадание? 

За мен всеки човек е огледало, в което се оглеждаме ние самите. Ако нямаш емпатия към другия, ти нямаш емпатия и към себе си. Ако не обичаш ближния, не обичаш и себе си. Ако си лицемерен с другия, си лицемерен и със себе си. Не можеш да избягаш от това. Понякога си състрадателен към себе си, но само привидно. И родителят вътре в теб по никакъв начин не помага на детето в теб, което в този момент плаче безутешно. А това е единствената му работа.

Но дали за страдащия човек има такова значение дали му съчувстваме искрено, или не? Според мен дори маската на състрадание помага. Може би защото изцяло вярвам на казаното от Кърт Вонегът: „Внимавай на какво се преструваш, защото ти си това, на което се преструваш.“ Искаме или не, в един момент ние се срастваме с маските, които носим.

Съгласна съм. Но тук искам да направя едно уточнение. Първо, човекът, който може най-добре да ти помогне, си ти самият – никой друг. В теб е силата да се издърпаш за косата и да се извадиш от блатото.

Другото е, че има „езици на любовта“. И всеки от нас говори на езика на своята любов. Всеки обича посвоему. И тук се появяват трудностите във връзката с другия.

Например някои хора имат нужда, когато са зле, просто да седна до тях, да ги прегърна и да помълчим заедно. За мен обаче това не е достатъчно. Аз бързам да вляза в ролята на майка (все пак съм зодия Рак) и да предложа решение, да посоча изход, да запаля светлина в тунела им. Те обаче възприемат това не като подкрепа, а като омаловажаване на проблема и страданието им. Думите ми не ги успокояват. Напротив – ожесточават ги. Така понякога всичко, което се очаква от мен, не е решение или план за действие, а защитено пространство, в което една друга душа да се отпусне и да се разпадне.

Искам да кажа, че да обичаш истински означава да се научиш да говориш на езика на любовта на другия. И аз продължавам да се уча на този чужд за мен език.

Дължим го на другите. Дължим го и на себе си.


* Рене Карабаш (Ирена Иванова) е поетеса, писателка, сценаристка и драматург. Името ѝ придобива световна известност покрай романа „Остайница“, който е преведен на 25 езика и печели множество литературни отличия у нас и в чужбина. През 2026 г. е включен и в краткия списък за Международната награда „Букър“. Рене е главна сценаристка на сериала на БНТ „Те, вълните“, а за главната си роля във филма „Безбог“ получава редица филмови награди за най-добра актриса.

Рене е основателка на Академията за писатели „Заешка дупка“, в която преподават изявени поети, писатели и сценаристи. В момента тече прием за есенното издание на Академията с писателски курсове, като „Тайните на трилъра“ с ментори Александър Чобанов и Емил Минчев и гост-лектор криминалния психолог Тодор Тодоров, както и няколко нови терапевтични курса по библиотерапия, писане за вътрешна свобода и терапевтично кинцуги. Повече информация може да получите на сайта на „Заешка дупка“ или на ел. поща: [email protected]
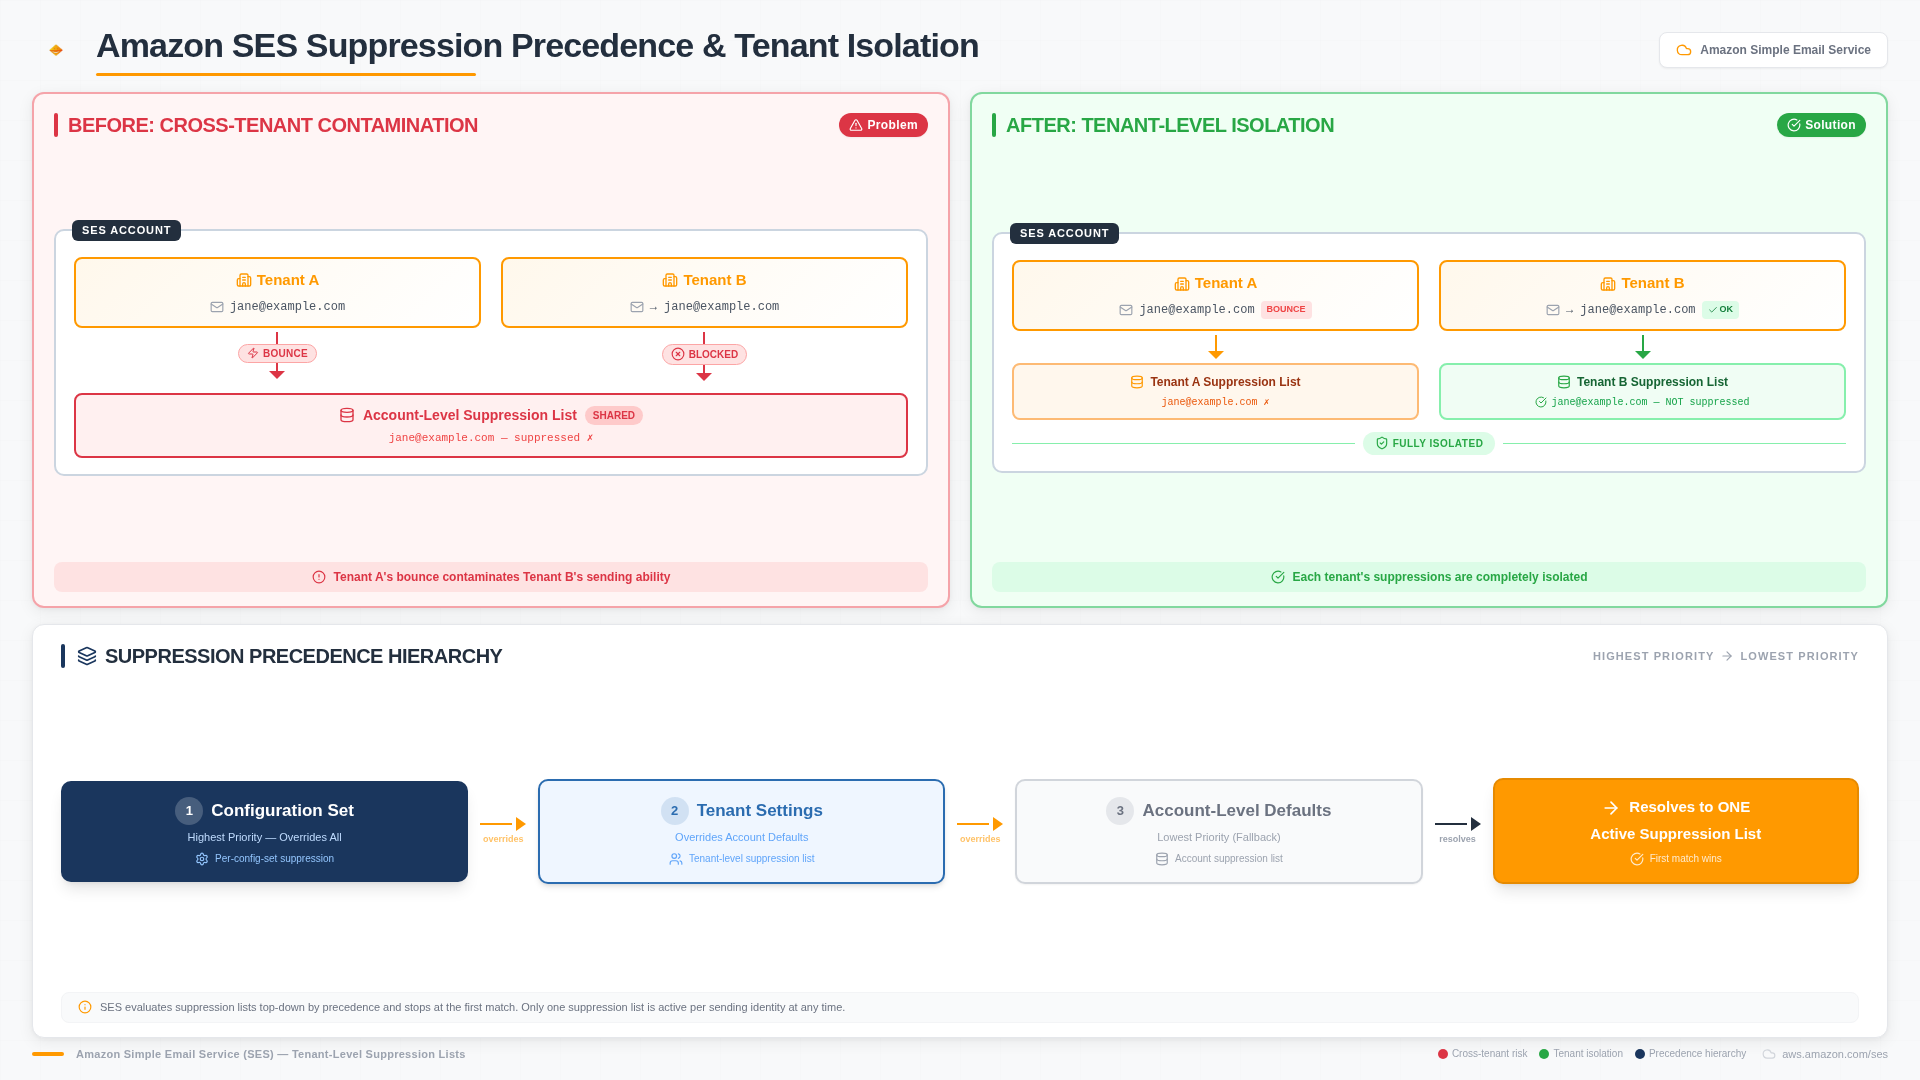
Google Is Suing Chinese Scammers Who Are Using Gemini

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/google-is-suing-chinese-scammers-who-are-using-gemini.html

Not sure this will have any effect, but I support the effort:

According to Google’s legal filing, Outsider Enterprise operates through Telegram. The group offers phishing-as-a-service to individuals who may not be technically savvy enough to set up fraudulent websites and text campaigns on their own. In its Telegram channels, Outsider Enterprise reportedly provided instructions on how to use Google’s Gemini AI to create websites that imitate those of Google, YouTube, and government agencies such as New York’s E-ZPass. The group offered nearly 300 scam templates.

[…]
Google worked with AT&T, Verizon, and T-Mobile to block many of these malicious text messages, and Google notes that its on-device scam detection in Google Messages probably helped reduce the number of successful phishing attempts, too. This AI-powered feature apparently stops 10 billion scam texts every month, so it’s fair to expect it caught at least some Outsider Enterprise activity.

Another article.

На трапезата на европейското разширяване – домакини, гости и нежелани посетители

Post Syndicated from Анахит Хачикян original https://www.toest.bg/na-trapezata-na-evropeyskoto-razshiryavane-domakini-gosti-i-nezhelani-posetiteli/

На трапезата на европейското разширяване – домакини, гости и нежелани посетители

Двайсет и седем високопоставени лица са седнали на една голяма кръгла маса и вечерят. Всеки има различни ястия пред себе си и е платил различна цена за куверта, но всички имат право на мнение за основното ястие, както и дали да бъдат поканени други участници. Един е напуснал през 2020 г. по невнимание и сега горчиво съжалява и обмисля да се върне. Още десетина чакат да влязат, някои вече стоят непосредствено пред вратата на трапезарията. Други са в самото начало на дългия коридор, а един от 1987 г. звъни на входната врата, но за пореден път е оставен „замръзнал“ навън заради непристойно поведение. Двама пък са желани гости, но техните собствени трапези са по-богати от тази, на която са поканени. Един се двоуми от 2009 г. и през август пак ще решава иска ли да вечеря с останалите, или не. Мнозина от самите вечерящи периодично се оплакват и негодуват, но знаят, че общата трапеза ще ги засити повече, отколкото ако решат да се хранят сами.

Приблизително така може да се изобрази разширяването на Европейския съюз, обявено за един от приоритетите на новия мандат на Европейската комисия. Войната в Украйна превърна обещанието за членство в ЕС в съвсем обозрима и конкретна перспектива не само за нападнатата държава, но и за страните от Западните Балкани, които отдавна чакаха в коридора, и сега изведнъж стана неудобно да се правим, че не ги забелязваме. А принципът „Съединението прави силата“ изглежда все по-утешителен в съвременния непредвидим свят.

Западните Балкани на много скорости

Черна гора, най-напреднала за момента в преговорния процес, води усилена имиджова кампания под лозунга „28 до 28“ – идентифицирайки се като „епицентър на еврооптимизма“ и надявайки се да стане 28-мата страна членка на ЕС до 2028 г. Гърция, която по време на председателството си на ЕС през 2003 г. игра ключова роля в подготвянето на предишното голямо присъединяване на десет страни през 2004 г., вече заяви готовност да направи необходимото за Черна гора в края на следващата година, когато пак ще е начело на ЕС. Европейският парламент също потвърди в годишния си доклад, приет на 17 юни на пленарната сесия в Страсбург, че Подгорица продължава да бъде най-напредналата от всички кандидат-членки, следователно вероятно ще бъде първата, която ще се присъедини.

По време на същата пленарна сесия Европейският парламент констатира, че Албания изостава заради корупция и вътрешнополитически проблеми, Босна и Херцеговина – заради недостатъчни реформи. А Северна Македония беше призована да направи необходимите конституционни промени, за да реши проблемните въпроси, включително тези, които са свързани с отношенията ѝ с България.

Косово, кандидатствала за членство през 2022 г., все още няма статус на страна кандидатка и не води преговори не само защото не е достатъчно подготвена, както се казва в последния доклад. По-сериозната причина е, че независимостта ѝ не е призната от 5 страни членки на ЕС (Испания, Словакия, Румъния, Гърция и Кипър), което блокира Съвета да придвижи процеса напред.

Сърбия, за която докладът ще бъде гласуван отделно през юли, се очаква да бъде силно разкритикувана заради флиртовете си с Русия и Китай, подобно на критиките към Грузия – също страна кандидатка от края на 2023 г. Пътят към членството на Грузия е замразен заради отявлените антидемократични закони, приети след изборите през 2024 г., включително за чуждестранните агенти, любим и на българското „Възраждане“. Турция също е със замразена кандидатура още от 2018 г. по сходни причини, свързани с върховенството на закона и демокрацията – критики, които се повтарят ежегодно в докладите на Европейския парламент и които като че ли се приемат с все по-голямо пренебрежение на Босфора.

Украйна и Молдова по бързата процедура, но колко бързо?

Докато положението със Западните Балкани и Турция е относително ясно, защото тези страни отдавна са в чакалнята на ЕС, Украйна и Молдова кандидатстваха през 2022 г. и присъединяването им все по-често се споменава като неотложно. Особено след като Виктор Орбан, основният отявлен опонент на украинското членството, слезе от унгарската политическа сцена. Сред най-големите привърженици на идеята са скандинавските и балтийските държави, които в същото време се чувстват най-застрашени от Русия. За да ускорят преговорите между Украйна и ЕС, те дори сформираха специална група от съветници с опит в европейските дела и дипломацията – привилегия, с която балканските страни не разполагаха.

Въпреки привидния ентусиазъм обаче подходът на ЕС е предпазлив не само защото преговорите с Украйна и Молдова все още са в самото начало. Влизането на Черна гора в ЕС ще означава присъединяване на малко над 600 000 души към населението на ЕС, а населението на Украйна е около 40 милиона… Това означава, че Украйна ще се нареди на пето място в Съюза по брой на населението и на първо по територия. Тя ще има приблизително същия брой евродепутати като Испания и Полша – между 53 и 60, и ще разполага със същата тежест като тях при гласувания в Съвета на ЕС. От друга страна, ще се нуждае от много средства, за да се възстанови и развие икономически. Но и ще може да подпомогне ЕС в амбициите му за самостоятелна отбрана, тъй като напредна значително в тази област в сравнение с всички други страни от ЕС.

Освен че новите гости трябва да спазят определени изисквания, за да седнат на общата трапеза, и домакините трябва да са готови да ги посрещнат.

Така нареченият капацитет на усвояване на ЕС (absorption capacity) се отнася до политическото, финансовото и институционалното приспособяване на Съюза към по-голям брой страни членки. Това включва както големи и сериозни въпроси, като бюджета и оперативните програми, така и логистични детайли, отнасящи се до необходимостта от нови офиси и сгради, които да приютят бъдещите евродепутати, комисари, дипломати и служители.

За да забави ритъма, без да разочарова Украйна, Германия вече предложи като междинна стъпка асоциирано членство на Украйна, което да даде достъп до определени политики, но без право на глас. Идеята бе отхвърлена от украинския президент Володимир Зеленски като „несправедлива“. Новият унгарски лидер Петер Мадяр подкрепи отварянето на първите преговорни глави между Киев и Брюксел, но настоя да не се избързва. Той обеща референдум в Унгария след 10–15 години, ако всички глави са затворени от Украйна за това време.

Молдова, от друга страна, доскоро беше неформално обвързана с Украйна, тъй като Европейската комисия разглеждаше в един пакет присъединителния процес с двете страни, но „със започването на преговорите всяка страна е отговорна за себе си“, както каза Урсула фон дер Лайен. Присъединяването и на двете държави ще затвърди евроатлантическата им ориентация и ще ги спаси от руското влияние, но предстои да разберем дали това може да стане еднакво бързо и за мирна Молдова, и за Украйна, в която войната продължава. Ако се стигне до блокаж, Кишинев разполага с резервен вариант: да се присъедини към Румъния и така автоматично да влезе в ЕС. Според молдовския вицепремиер, ако присъединяването не приключи до 2028 г., може да се пристъпи към това алтернативно решение.

На север от Брюксел: стъпка напред, две назад

Бившите източни и балкански социалистически страни напират да влязат в ЕС не само по икономически и политически причини, а и за да затвърдят принадлежността си към европейските ценности и да запълнят пукнатините, оставени от пропастта на Студената война. Различна е обаче мотивацията на други европейски държави, които периодично се колебаят да се присъединят към ЕС или да се върнат, след като доброволно са го напуснали.

Два референдума на норвежците (1972 и 1994 г.) и един на швейцарците (1992 г.) оставиха двете държави извън Съюза, макар че и двете имат достъп до общия пазар на ЕС, част са от Шенген и се възползват от много общи програми на основата на двустранни споразумения. Същото разширено партньорство ЕС е изградил и с Лихтенщайн и Исландия. Рейкявик обаче подаде кандидатура за членство през 2009 г., оттегли я малко по-късно, но отново се активизира след като Русия нападна Украйна. И ще организира референдум за членство през август 2026 г.

Несъмнено най-големият прецедент в историята на отношенията между ЕС и европейските държави беше създаден от Великобритания, която напусна през 2020 г., след проведен референдум. Резултатите от него учудиха дори тези, които инициираха провеждането му. В новия документален филм на BBC, посветен на десетгодишнината от злополучния референдум: „Брекзит: много британска гражданска война“, са включени главни действащи лица от тогавашната политическа сцена. Сред тях са консервативният премиер Дейвид Камерън, организирал референдума, и Борис Джонсън, също консерватор и защитник на Брекзит. Те споделят изненадата си от крайния резултат и неподготвеността си за него: докато предварителните социологически проучвания сочат, че повече от половината англичани искат да останат в ЕС, гласуващите решават точно обратното.

Десетгодишнината от референдума беше повод за много равносметки и анализи,

в които се анализират загубите на Острова от оттеглянето му от европейската трапеза и се разобличават лъжите зад кампанията преди референдума. Отчитат се намалени търговски и икономически показатели, Лондон е загубил привлекателността си на световна финансова столица, а проблемите с нелегалната имиграция още по-трудно могат да се решат сега, когато Великобритания трябва да се справя сама. През последните месеци лейбъристкото правителство на Киър Стармър зачести изявленията си в полза на нови преговори с ЕС и евентуален ход назад: Breturn. Обществената подкрепа за завръщането прогресивно расте през последните десет години, а от страна на Брюксел и на европейските граждани винаги е имало интерес и готовност англичаните пак да седнат на общата трапеза.

Но планираната среща между ЕС и Великобритания на 22 юли в Брюксел, на която трябваше да бъде обсъдено новото засилено сътрудничество в редица области, беше отложена, след като Стармър подаде оставка, а вероятният следващ британски премиер Анди Бърнам заяви още преди да бъде назначен, че връщането в ЕС няма да е приоритет. Засега въпросът остава открит, но не е изключено една или няколко други държави да влязат в ЕС, преди британците да решат какво искат да правят.

България: какво мислим ние за разширяването?

Дори след като приключи преговорния процес по всички глави, дадена държава не може да се присъедини, преди всички държави членки да са одобрили и ратифицирали това присъединяване. Проучване на Евробарометър от септември 2025 г. сочи, че 56% от европейците подкрепят бъдещи разширявания, като Украйна се радва на най-голяма подкрепа сред страните кандидатки (най-висока в Швеция – 91% и Финландия – 81%), а Турция е най-непопулярна (най-ниска сред кипърците – 13% и австрийците – 19%). Българските резултати обаче са различни: 63% от анкетираните подкрепят Сърбия, после идват Босна и Херцеговина, Черна гора, Молдова, Грузия и Турция, Албания и Косово с подкрепа между 50 и 40%. На последно място сред българските анкетирани се нареждат Украйна (31%) и Северна Македония (32%). Само в Унгария и Чехия подкрепата за Украйна е толкова ниска, колкото и у нас.

Подкрепа в България за присъединяването на страните кандидатки към ЕС

Сърбия
63%

Босна и Херцеговина
53%

Черна гора
52%

Република Молдова
51%

Грузия
47%

Турция
46%

Албания
43%

Косово
40%

Северна Македония
32%

Украйна
31%

Източник: Проучване на Евробарометър, септември 2025 г. (делът на отговорите „Общо подкрепям“)

Логично е да се запитаме защо в България сме по-склонни да приемем в ЕС една голяма държава като Турция, която коренно се различава от останалите в географско, политическо, културно и религиозно отношение и за момента е много далеч от демократичните стандарти, отколкото да подкрепим други две държави, с които споделяме общо славянско наследство? Докато липсата на подкрепа за Северна Македония е пряко свързана с проблемите в двустранните отношения между София и Скопие, зад отрицателното отношение към Украйна ясно прозират българските симпатии към Русия. Тук фразата „Врагът на моя враг е мой приятел“ е преобърната на „Врагът на моя приятел е мой враг“. Ето защо не искаме да седим на една трапеза с този враг, да не би това да постави в риск много „по-важните“ ни приятелства.


Изразеното мнение е лично и не представлява позицията на Европейския парламент.

Uncover new performance insights using Amazon detailed performance statistics on Windows

Post Syndicated from Xinze Zhang original https://aws.amazon.com/blogs/compute/uncover-new-performance-insights-using-amazon-detailed-performance-statistics-on-windows/

The primary storage solutions for EC2 Windows instances, Amazon EC2 Instance Store and Amazon Elastic Block Store (Amazon EBS) , now provide detailed performance statistics for real-time monitoring. Real-time monitoring enables you to gain visibility into key performance metrics, such as latency, throughput, and IOPS, allowing you to detect and address potential bottlenecks or issues proactively.

In this post, we explore how to use detailed performance statistics for both Amazon EBS and Instance Storage on Windows environments. These new metrics provide sub-minute granularity, offering real-time visibility into storage volume performance across both storage types. You can access these statistics directly from your Amazon EBS NVMe/Amazon Instance Storage NVMe device attached to the Amazon Elastic Compute Cloud (Amazon EC2) instance and use them to monitor I/O performance at the storage level. We also provide examples of how to use these statistics to quickly assess EBS volume/Storage health and identify performance bottlenecks, which improve both the reliability and performance of your applications. When creating or attaching EBS volumes, enable encryption at rest using AWS Key Management Service (AWS KMS) to protect your data. For more information, see Amazon EBS encryption in the Amazon EC2 User Guide.

Solution overview

Using the new Amazon EC2 Instance Store/Amazon Elastic Block Store (Amazon EBS) detailed performance statistics at the instance-level, this sample solution enhances observability and troubleshooting capabilities for latency-sensitive applications running on EC2 Nitro instances. We use the new nvme_amzn.exe tool to collect high-frequency statistics on I/O operations, latency, and queue length, enabling proactive troubleshooting.

As examples of how to use these granular metrics, this solution demonstrates how to validate the responsiveness of local storage and EBS volume, so that you can quickly identify any I/O interruptions. This solution helps you identify storage performance bottlenecks, which can be used to optimize the local storage and EC2 instance configurations for your workloads.

Prerequisites

This solution involves setting up an EC2 Nitro instance and an attached local storage to access detailed performance statistics for the local storage. This is a setup you likely already have if using Amazon EC2. To deploy the required components, you must complete the following steps:

  1. Launch an EC2 Nitro instance (or use an existing Nitro instance), and connect to it via Remote Desktop Protocol (RDP).
  2. Verify that your EC2 Windows instance includes AWS NVMe driver version 1.7.0 or later installed by following identify your driver type
  3. Identify the NVMe device associated with the local storage/EBS volume for which you want to query the stats. You can run the Get-Disk command in PowerShell to output all NVMe devices on the instance. For more information, see Map NVMe disks on Amazon EC2 Windows instance to volumes.

For this demonstration, we’ll monitor two storage volumes:

  • EBS volume (Disk 0): Serial Number vol01234567890abcdef_00000001.
  • Local storage (Disk 1): Serial Number AWSEXAMPLE1234567890_00000001.
  1. Ensure that nvme_amzn.exe is present in C:\ProgramData\Amazon\Tools by default.
  2. Use the nvme_amzn.exe tool, with administrator privileges, and pass the disk number as a parameter with different command. The returned output looks like the following.

Administrator: Windows PowerShell:

.\nvme_amzn.exe --help or nvme_amzn.exe /help

Users can see the EBS volumes devices mapping by default without passing the disk number as a parameter

.\nvme_amzn.exe

Users can view the specific device mapping by passing disk numbers or a single disk number as a parameter.

.\nvme_amzn.exe 0 1 2 3 4

Users can see the nvme controller details by using id-ctrl and pass the disk number as a parameter (JSON output can be retrieved by providing the --json or /json parameter to the tool)

# EBS volume
.\nvme_amzn.exe id-ctrl 0

# EC2 local storage
.\nvme_amzn.exe id-ctrl 1

.\nvme_amzn.exe id-ctrl 0 --json

Users can see the performance statistics for EBS/EC2 local storage volume by using stats and pass the disk number as a parameter (provide the --json or /json parameter to retrieve JSON output).

# EBS volume
.\nvme_amzn.exe stats 0
# Json format
.\nvme_amzn.exe stats 0 --json

# EC2 Local storage volume
.\nvme_amzn.exe stats 1
# Json format
.\nvme_amzn.exe stats 1 --json

In addition, for EC2 local storage volume, by providing the --details/-d option, you can see the histogram of 5 different IO bands: (0, 512 Byte], (512B, 4KiB], (4KiB, 8KiB], (8KiB, 32KiB], (32 KiB, MAX].

.\nvme_amzn.exe stats 0 --details

The following example shows NVMe log output with cumulative statistics. The statistics indicate read/write operations, bytes transferred, and time spent processing operations (in microseconds). They also show the number of microseconds in which the application attempted to exceed the Amazon EBS or Amazon EC2 Instance Local Storage IOPS/throughput limits

EBS volume:

EC2 local storage volume:

Also included in the following figures are read and write I/O latency histograms, with each row representing the total number of I/O operations completed so far within a specific bin of time (in microseconds).

These statistics are presented as cumulative counters up to the time at which the command is executed. The command can be run at the desired interval, for example, every 15 seconds, with each subsequent output reflecting the updated cumulative totals for the metrics. Calculating the difference in the statistics across the last two outputs allows you to derive insight into the instance storage profile over the given 15 second period.

Deriving insights from the Amazon Instance Storage/EBS volume detailed performance statistics

You have set up monitoring using these detailed performance statistics, now we can demonstrate the different ways you can use these statistics.

As mentioned in the preceding section, you can use the detailed statistics to view I/O latency histograms to observe the spread of I/O latency within the period. You can use the read/write operations and time spent statistics to calculate the average latency. Using the detailed statistics allows you to view the average latency at a sub-minute granularity.

Here are four examples for you to use the statistics to shed light on key performance metrics.

Scenario 1: Identifying unresponsive state of an EBS volume

In this scenario, we discuss how to use Amazon EBS detailed performance statistics to observe when an EBS volume isn’t responding to I/O operations. If you observe multiple intervals where your volume is unresponsive, then you can take actions, such as replacing the affected volume or stopping and restarting the instance to which the volume is attached. In most cases, when your volume becomes unresponsive, Amazon EBS automatically diagnoses and recovers your volume within a few minutes.

To identify if your volume is unresponsive, you can use the following steps to determine whether I/O disrupted on your volume:

  1. Identify the EBS volume’s NVMe device to troubleshoot
  2. Collect stats for the device at the desired intervals
  3. Compare the stats to check if the EBS volume is unresponsive

Step 1: Identify the EBS volume’s NVMe device to troubleshoot

1. Identify the NVMe device associated with the EBS volume on the instance by using the nvme_amzn.exe tool.

.\nvme_amzn.exe

Step 2: Collect stats for the device at the desired intervals

1. Collect the Amazon EBS detailed performance statistics directly from the device by using the nvme_amzn.exe tool:

# EBS volume disk0
.\nvme_amzn.exe stats 0

Step 3: Compare the stats to check if the EBS volume is unresponsive

1. From the output, consider the following three fields for this scenario: Total Read Ops, Total Write Ops, and Queue Length.

2. Issue the same ebsnvme command after a desired interval (for example: after 15 seconds), so that you can compare how Total Read/Write I/Os have progressed at the Amazon EBS level.

3. From the detailed performance statistics collected approximately 15 seconds apart, we make the following key observations

  • Total Read Ops increased from 1421153 to 1423480, indicating 2327 Read operations completed in the 15 second span.
  • Total Write Ops increased from 13835137 to 13846338, indicating 11201 Read operations completed in the 15 second span.
  • Queue Length stayed between 0 and 6, indicating that the application was issuing I/Os to the EBS volume. If you see a gradual increase in the Queue Length, then it would reflect a buildup in queued I/Os.

This shows that the EBS volume is still driving I/Os that it is receiving, which rules out the EBS volume as the source of observed degradation in application performance. If we had seen an increase in the Queue Length along with 0 Read/Write Ops processed during the period, then it would reflect an unresponsive EBS volume.

If you would like to validate your mechanisms of identifying unresponsive EBS volumes, refer to the Conducting chaos engineering experiments on Amazon EBS using AWS Fault Injection Service blog post, which walks through how to set up an AWS Fault Injection Service Pause I/O experiment.

Scenario 2: Identifying bottlenecks in storage performance on EBS

Amazon EBS detailed performance statistics can also be used to configure the appropriate performance characteristics for your EBS volume and EC2 instance based on the performance needs of your application. The EBS Volume Performance Exceeded and EC2 Instance EBS Performance Exceeded statistics indicate the duration for which your workload consistently attempted to drive IOPS or throughput that is greater than your volume or your instance’s provisioned performance in a given period. Exceeding either the volume’s or instance’s provisioned performance can result in elevated latency on your workload. For this scenario, consider the same application as the one used in scenario 1.

Complete the following steps to check if EBS volume performance is correctly provisioned:

1. Select the EBS volume’s NVMe device to check
2. Collect stats for the device at the desired intervals
3. Compare the stats to check if the EBS volume is exceeding provisioned performance

Step 1. Select the EBS volume’s NVMe device to check

1. This step is the same as Step 1 discussed previously in scenario 1.

Step 2. Collect stats for the device at the desired intervals

1. Similar to Step 2 discussed in scenario 1, access the detailed performance statistics across two points in time.

2. Consider the EBS Volume Performance Exceeded and EC2 Instance EBS Performance Exceeded statistics from the EBS NVMe device.

$DiskNumber = 0
$Interval = 15

while ($true) {
    Write-Host "=== $(Get-Date -Format 'yyyy-MM-dd HH:mm:ss') ===" -ForegroundColor Cyan; & "C:\ProgramData\Amazon\Tools\nvme_amzn.exe" stats $DiskNumber
    Write-Host ""
    Start-Sleep -Seconds $Interval
}

Step 3: Compare the stats to check if the EBS volume is exceeding provisioned performance

1. In the following example output, you can see the EBS Volume Performance Exceeded statistic increasing by 26813772 microseconds. This shows the workload running on EBS volume vol-EXAMPLEabcd1234 has attempted to drive more IOPS than provisioned on the underlying EBS volume, which can impact the volume’s I/O latency. We recommend that you increase the performance of your volume to make sure that you have sufficient provisioned performance for your application’s needs.

2. In the following example output, driving a different workload on the instance allows us to see that the volume has exceeded the provisioned IOPS performance at the attached EC2 instance level. In this case, up-sizing to a larger instance size can improve the performance of your application.

3. A synthetic load generator for Oracle called Silly Little Oracle Benchmark (SLOB) could also be used to simulate workloads on Oracle databases, while monitoring the Amazon EBS statistics to see which volume or instance is becoming the bottleneck.

It’s important to have the right instance and volume configurations to avoid performance bottlenecks to your application. Refer to the EBS volume types documentation for more information on the different EBS volume types, and the Amazon EBS-optimized documentation to understand how to select the optimal combination of EC2 instance and EBS volume suited for your application. These statistics are available at up to a one-second granularity, which allows you to effectively perform these checks in real-time and initiate volume modifications to optimize volume characteristics as needed.

Scenario 3: Identifying bottlenecks in storage performance on instance storage volume

Amazon Instance Storage detailed performance statistics can be used to configure the appropriate performance characteristics for your application. The “EC2 Instance local storage Performance Exceeded” statistics indicate the duration for which your workload consistently attempted to drive IOPS or throughput that is greater than your rate limit in a given period. Exceeding the throttle value can result in elevated latency on your workload.

For example, i3en.xlarge can support up to 85,000 read IOPS, 65,000 write IOPS, 634,765 KiB/S for read and 317,382 KiB/S for write. By using the detailed IO metrics, you can more efficiently determine if the instance meets your requirements.

Complete the following steps to check if the device meets your application needs:

  1. Select the instance storage device to check.
  2. Collect stats for the device at the desired intervals
  3. Compare the stats to check if the instance storage is exceeding the throttled value

Step 1. Select the Instance Storage NVMe device to check

Use the nvme_amzn tool and identify the NVMe device associated with the instance storage.

Step 2: Collect stats for the device at the desired intervals

$DiskNumber = 0
$Interval = 15

while ($true) {
    Write-Host "=== $(Get-Date -Format 'yyyy-MM-dd HH:mm:ss') ===" -ForegroundColor Cyan; & "C:\ProgramData\Amazon\Tools\nvme_amzn.exe" stats $DiskNumber
    Write-Host ""
    Start-Sleep -Seconds $Interval
}

Step 3: Compare the stats to check if the instance storage is exceeding throttle value

Take the following scenario as an example. At the very beginning, after the instance launch, both the IOPS and Throughput under “EC2 Instance local storage Performance Exceeded (us)” are 0s.

You start your applications and find that the application write does not meet your expectation. You can check the IO metrics afterwards. You see a lot of IO falls into the 1 ms to 2 ms range, which is unexpected.

By further checking the “EC2 Instance local storage Performance Exceeded (us)”. You found that the IO reached the allowed upper limit for up to 8 seconds, which indicates the i3en.xlarge would not meet your expectations. Select a larger instance size to address this.

It’s important to have the right instance size to avoid performance bottlenecks to your application. Refer to the ec2-instance-type-specifications documentation for more information on the different instance storage size to understand how to select the optimal instance size suited for your application. This tool helps you to effectively perform these checks in real-time.

Scenario 4: Identifying which block size caused the long latency on instance storage volume

You may have a mixed workload:

  • Data (either read or write) pattern with different block sizes like 4K and 128K.
  • Mixed read and write data pattern.

By using the --detail/-d switch from the NVMe CLI, you can identify the issue quickly and readjust the workload.

Example 1: High write latency from a workload

By further looking at the histogram of the block size range larger than 32 KiB, you can see that the larger IO caused high application latency, while other block sizes (like 8K) show no latency abnormality.

Example 2: Mixed read and write traffic

Some users will have a mix of read and write traffic. For example, some applications will do light read traffic (for example to read out some metadata) and heavy write. This may inadvertently impact the read latency. For example, an application is doing a read operation with a single IO of small block size. However, the user experiences high read latency. Examining the histogram breakdown, you could reasonably believe the heavy larger IO write may interfere with the read.

The detailed IO histogram for IO size larger than 512B but less than or equal to 4KB

The detailed IO histogram for IO size larger than 32 KiB

The user should consider smoothing out the write pattern to alleviate the read latency.

Cleaning up

If you created an EC2 instance and EBS volume for this exercise, then terminate and delete the appropriate instance and volumes to avoid future costs.

Conclusion

In this post, we presented a solution for accessing high-resolution performance statistics for Amazon EBS volumes and EC2 Instance Store at the instance level. These detailed metrics provide a real-time view into your underlying storage performance at sub-minute granularity, helping you to quickly root cause disruptions to your applications.

This approach also helps you identify performance bottlenecks caused by workloads exceeding your provisioned IOPS or throughput limits on Amazon EC2, EBS volumes, or EC2 Instance Store. Combined with Amazon CloudWatch metrics, which provide volume-level insights at one-minute granularity, these tools help give you the visibility you need to confidently diagnose and resolve storage-related performance issues.

The collective thoughts of the interwebz