Tag Archives: launch

Introducing Anthropic’s Claude Opus 4.7 model in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-anthropics-claude-opus-4-7-model-in-amazon-bedrock/

Today, we’re announcing Claude Opus 4.7 in Amazon Bedrock, Anthropic’s most intelligent Opus model for advancing performance across coding, long-running agents, and professional work.

Claude Opus 4.7 is powered by Amazon Bedrock’s next generation inference engine, delivering enterprise-grade infrastructure for production workloads. Bedrock’s new inference engine has brand-new scheduling and scaling logic which dynamically allocates capacity to requests, improving availability particularly for steady-state workloads while making room for rapidly scaling services. It provides zero operator access—meaning customer prompts and responses are never visible to Anthropic or AWS operators—keeping sensitive data private.

According to Anthropic, Claude Opus 4.7 model provides improvements across the workflows that teams run in production such as agentic coding, knowledge work, visual understanding,long-running tasks. Opus 4.7 works better through ambiguity, is more thorough in its problem solving, and follows instructions more precisely.

  • Agentic coding: The model extends Opus 4.6’s lead in agentic coding, with stronger performance on long-horizon autonomy, systems engineering, and complex code reasoning tasks. According to Anthropic, the model records high-performance scores with 64.3% on SWE-bench Pro, 87.6% on SWE-bench Verified, and 69.4% on Terminal-Bench 2.0.
  • Knowledge work: The model advances professional knowledge work, with stronger performance on document creation, financial analysis, and multi-step research workflows. The model reasons through underspecified requests, making sensible assumptions and stating them clearly, and self-verifies its output to improve quality on the first step. According to Anthropic, the model reaches 64.4% on Finance Agent v1.1.
  • Long-running tasks: The model stays on track over longer horizons, with stronger performance over its full 1M token context window as it reasons through ambiguity and self-verifies its output.
  • Vision: the model adds high-resolution image support, improving accuracy on charts, dense documents, and screen UIs where fine detail matters.

The model is an upgrade from Opus 4.6 but may require prompting changes and harness tweaks to get the most out of the model. To learn more, visit Anthropic’s prompting guide.

Claude Opus 4.7 model in action
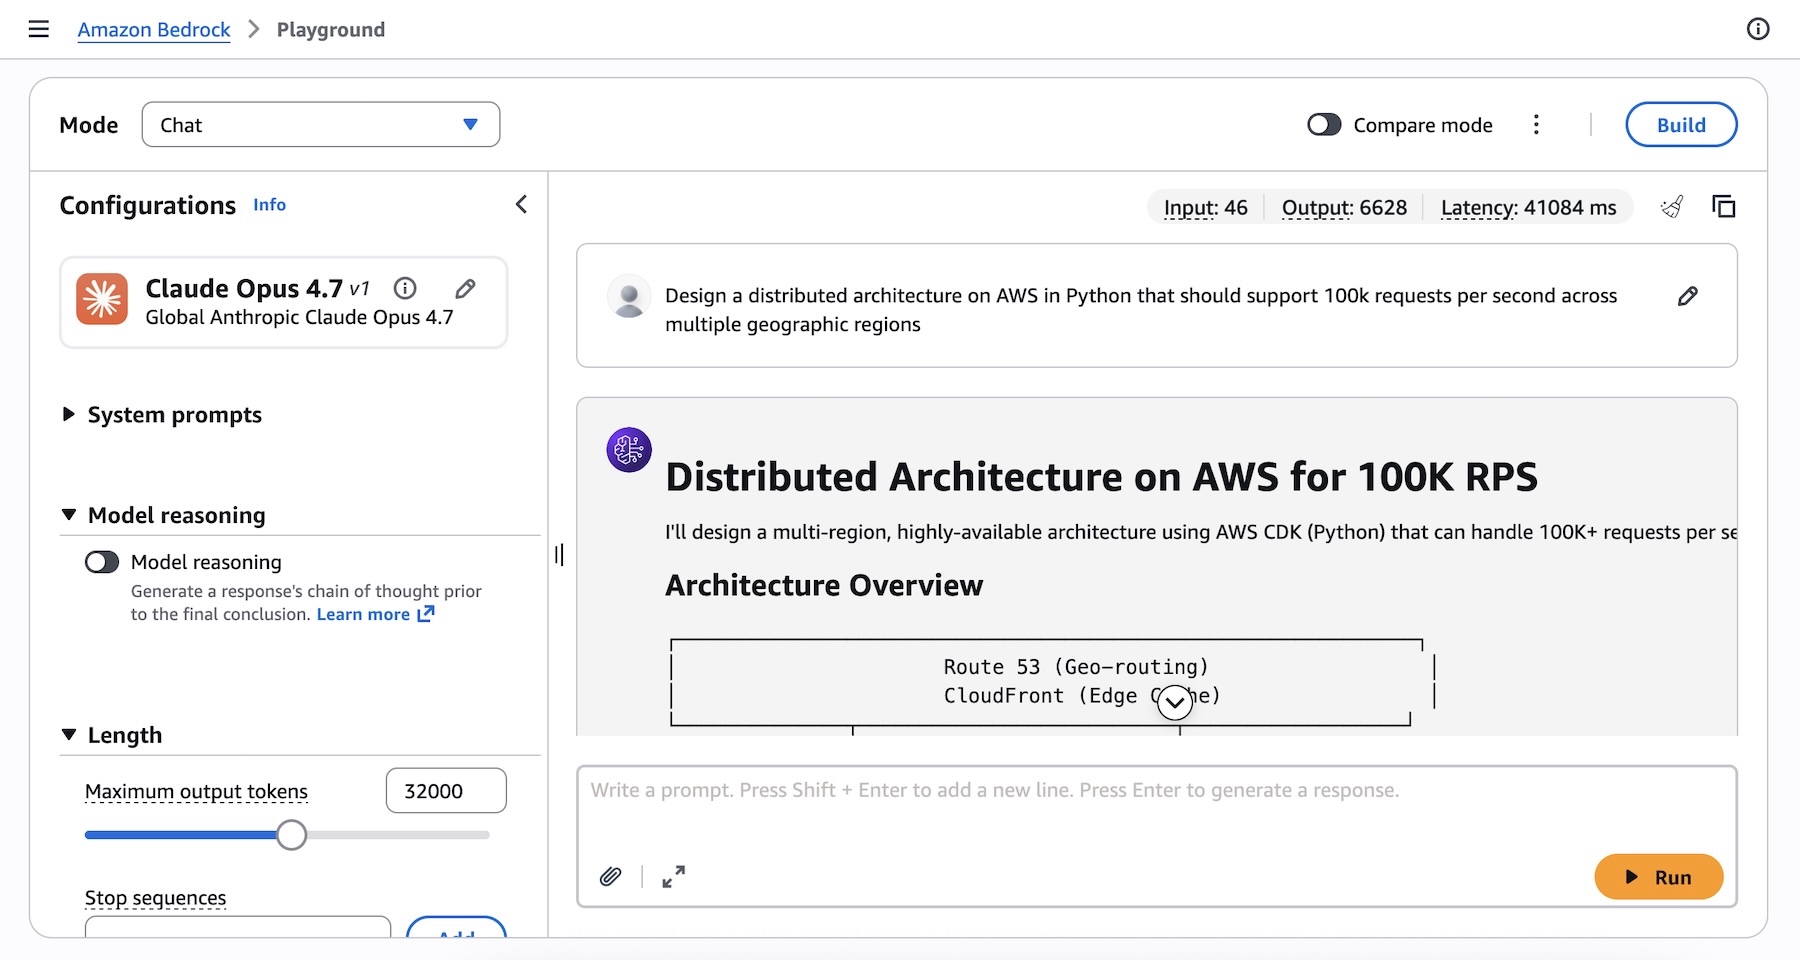
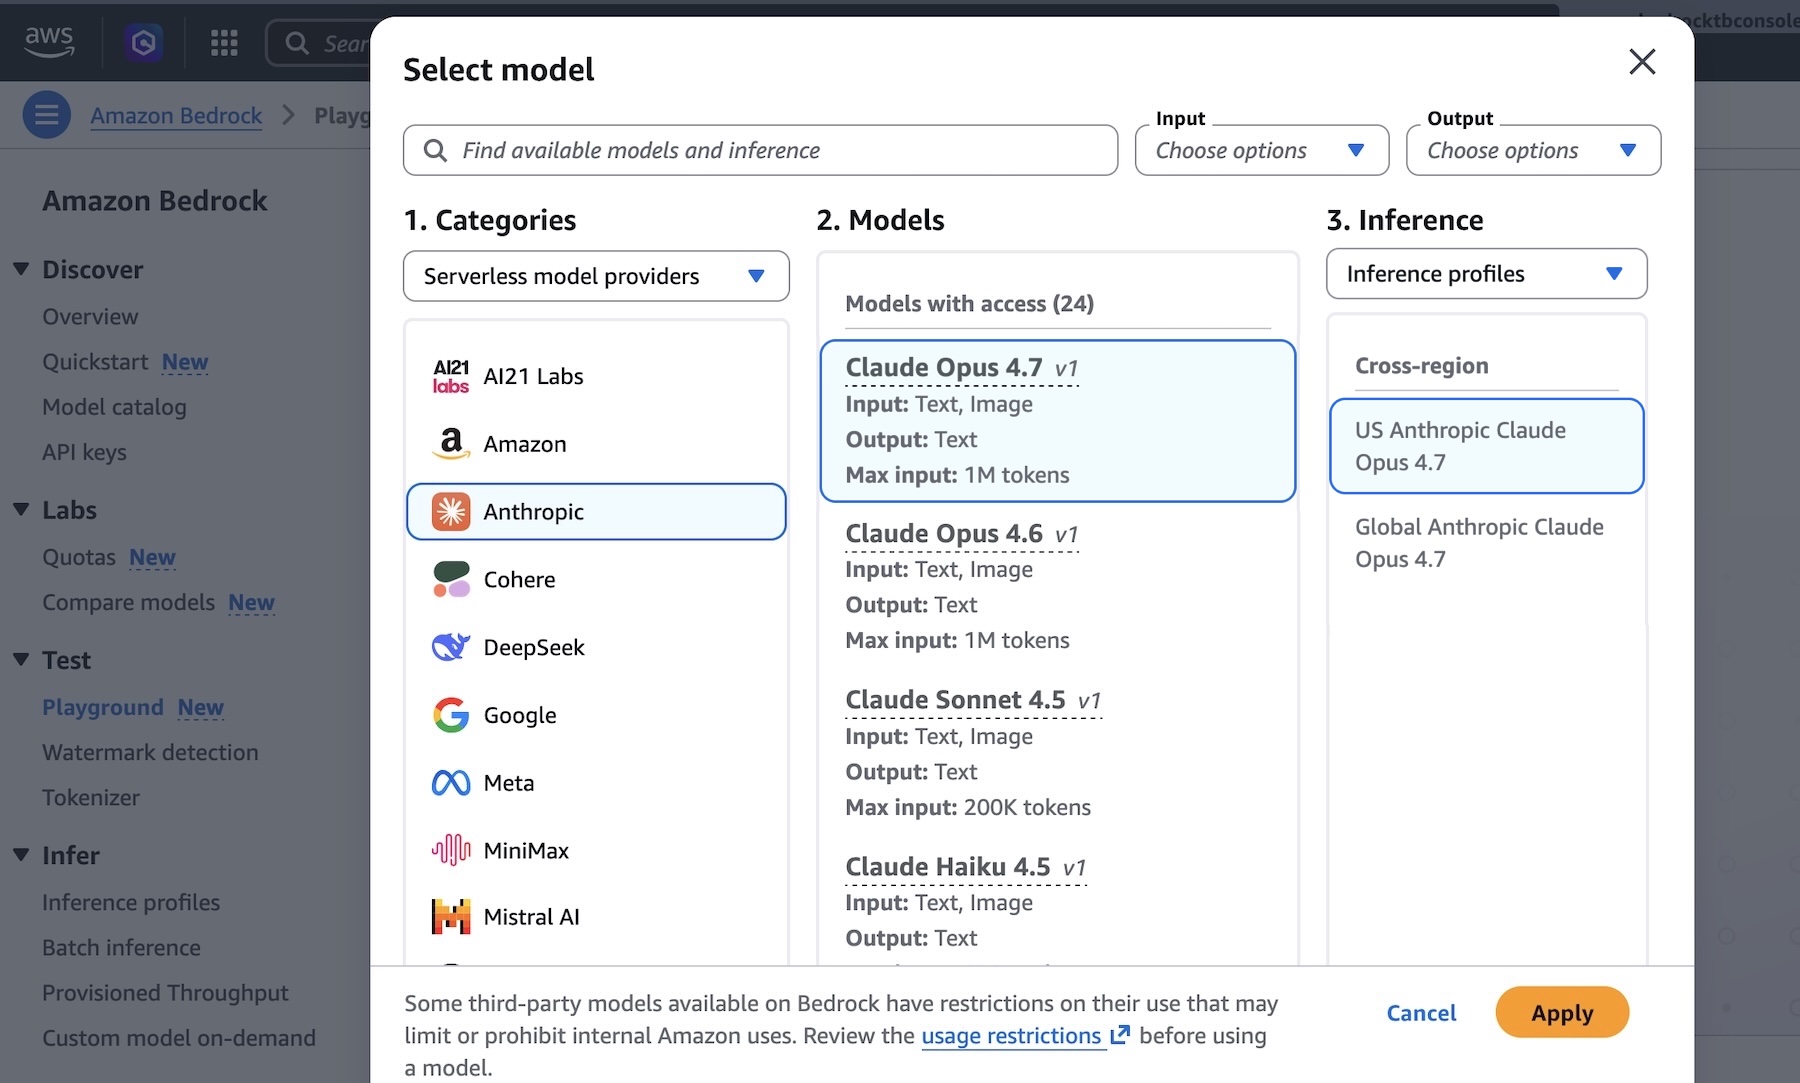
You can get started with Claude Opus 4.7 model in Amazon Bedrock console. Choose Playground under Test menu and choose Claude Opus 4.7 when you select model. Now, you can test your complex coding prompt with the model.

I run the following prompt example about technical architecture decision:
Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions.

You can also access the model programmatically using the Anthropic Messages API to call the bedrock-runtime through Anthropic SDK or bedrock-mantle endpoints, or keep using the Invoke and Converse API on bedrock-runtime through the AWS Command Line Interface (AWS CLI) and AWS SDK.

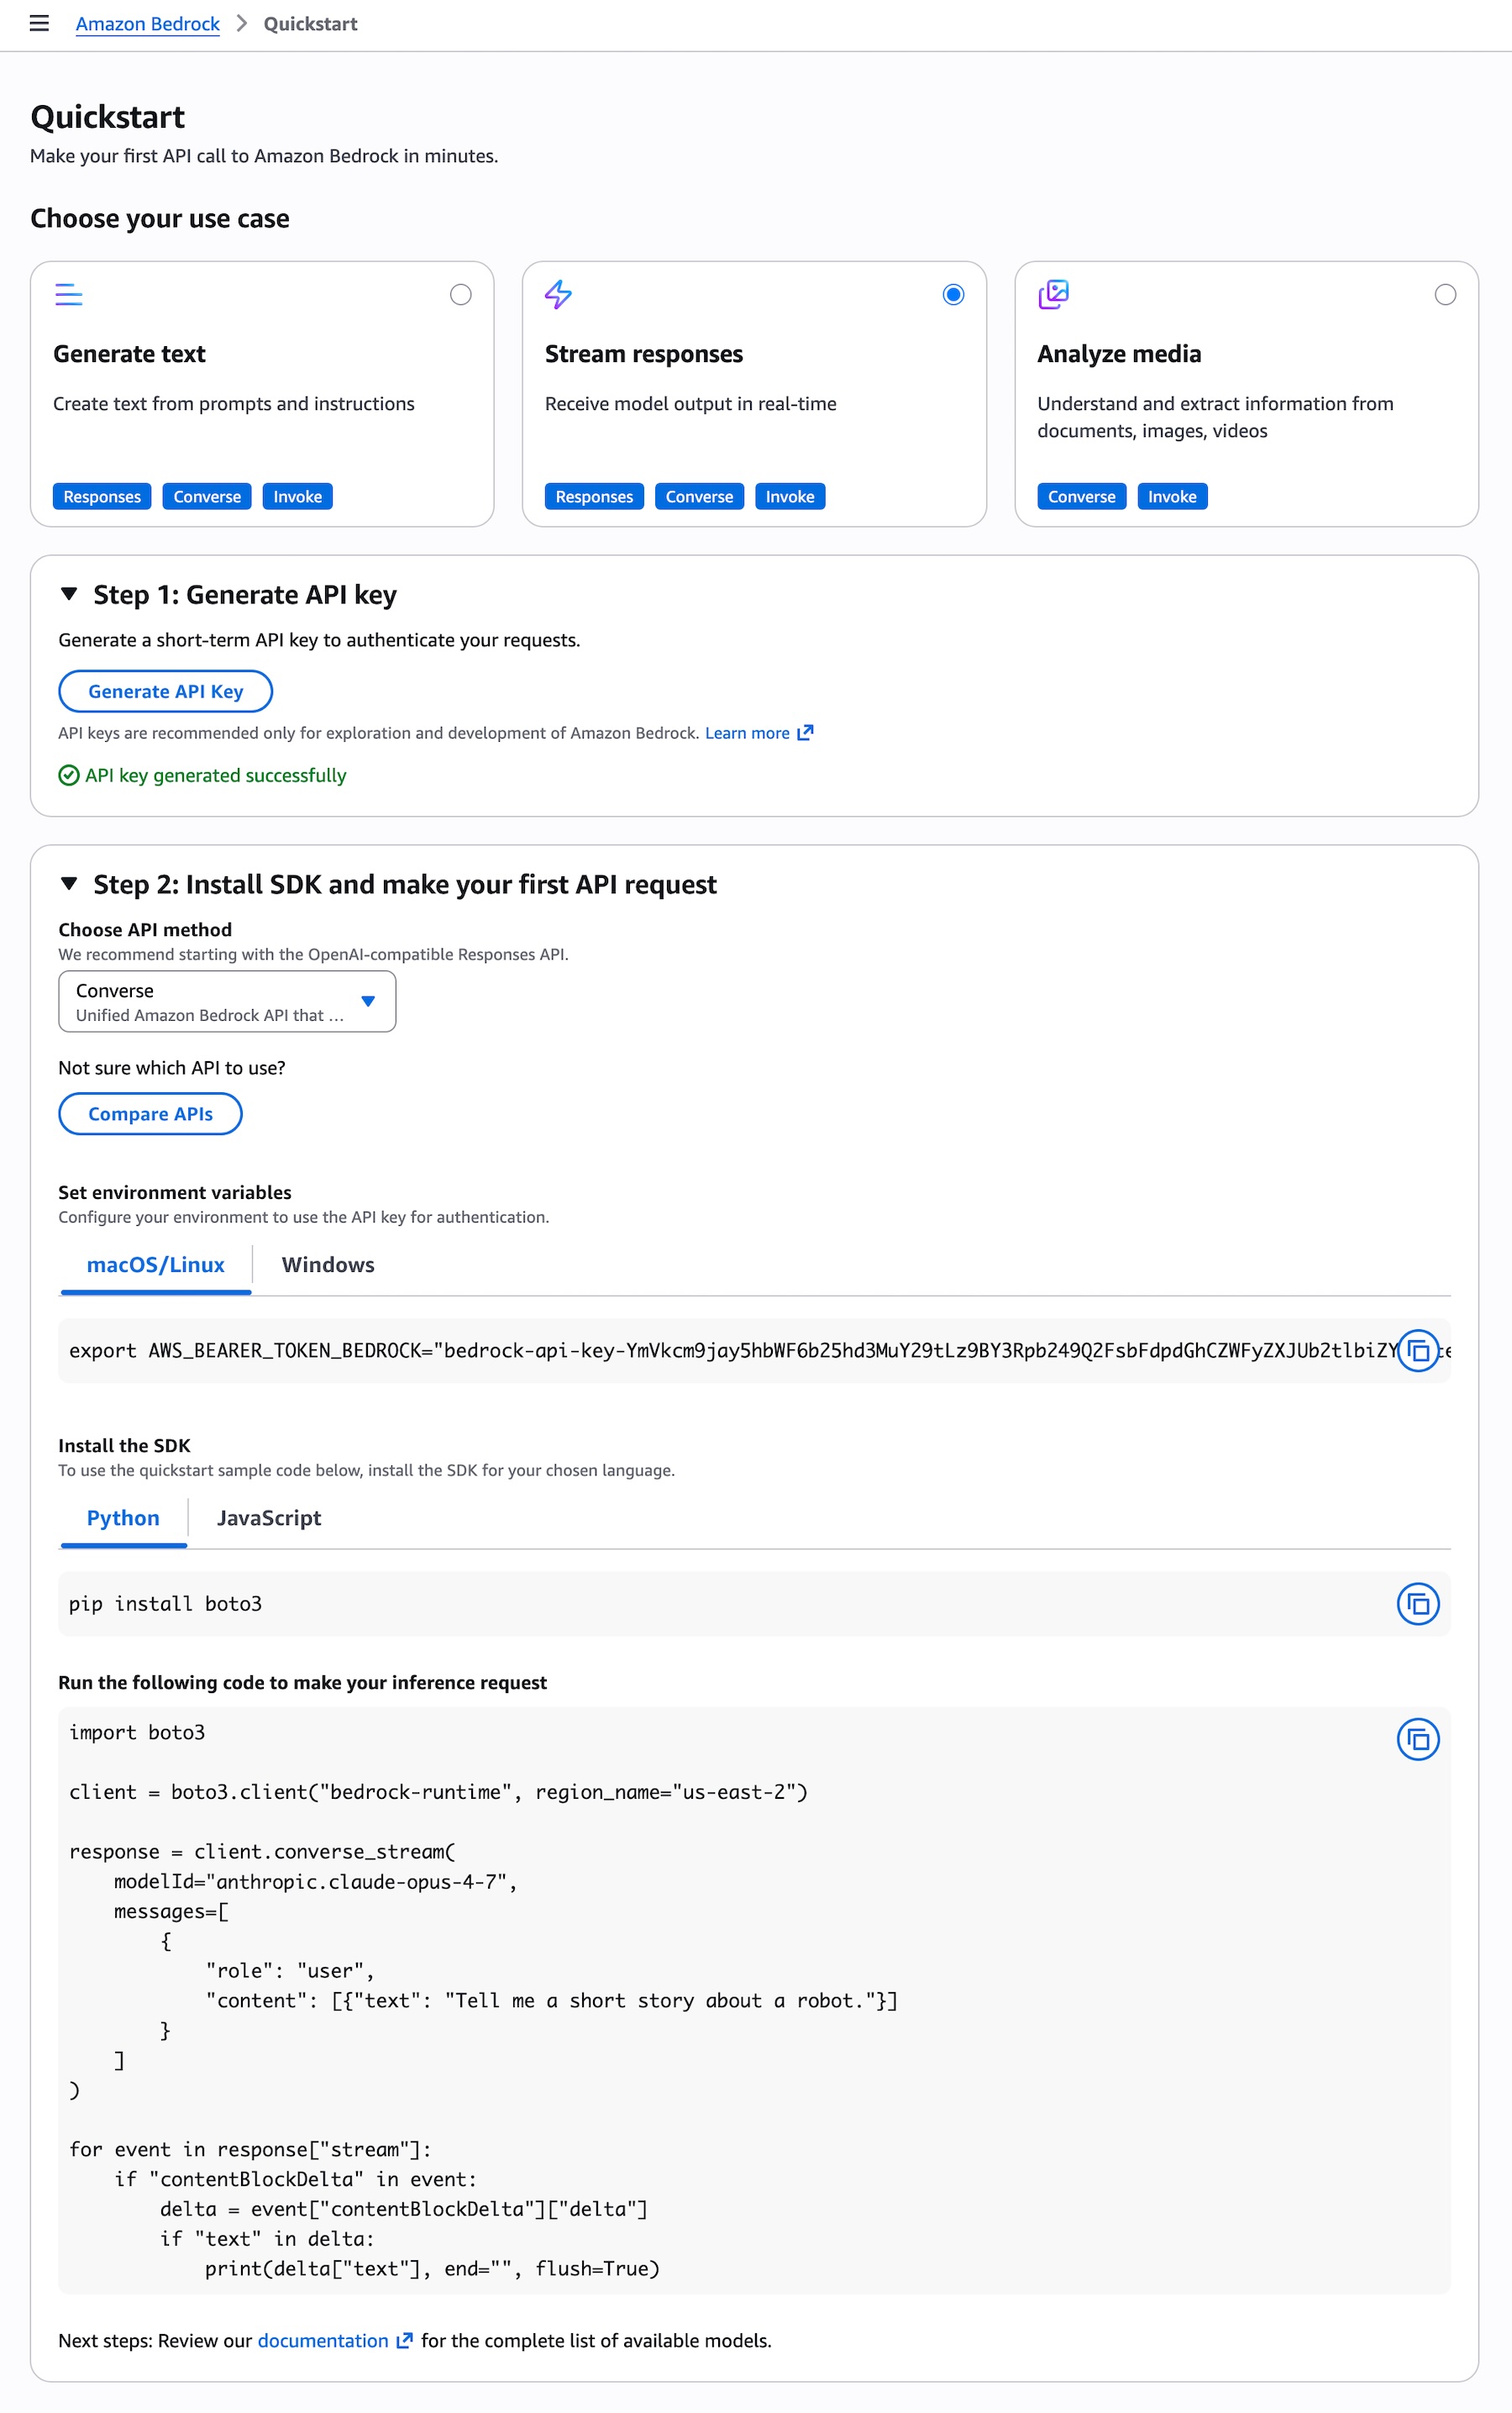
To get started with making your first API call to Amazon Bedrock in minutes, choose Quickstart in the left navigation pane in the console. After choosing your use case, you can generate a short term API key to authenticate your requests as testing purpose.

When you choose the API method such as the OpenAI-compatible Responses API, you can get sample codes to run your prompt to make your inference request using the model.


To invoke the model through the Anthropic Claude Messages API, you can proceed as follows using anthropic[bedrock] SDK package for a streamlined experience:

from anthropic import AnthropicBedrockMantle
# Initialize the Bedrock Mantle client (uses SigV4 auth automatically)
mantle_client = AnthropicBedrockMantle(aws_region=REGION)
# Create a message using the Messages API
message = mantle_client.messages.create(
    model="anthropic.claude-opus-4-7",
    max_tokens=2048,
    messages=[ 
	    {"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions"}
    ]
)
print(message.content[0].text)

You can also run the following command to invoke the model directly to bedrock-runtime endpoint using the AWS CLI and the Invoke API:

aws bedrock-runtime invoke-model \ 
 --model-id anthropic.claude-opus-4-7 \ 
 --region us-east-1 \ 
 --body '{"messages": [{"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."}], "max_tokens": 512, "temperature": 0.5, "top_p": 0.9}' \ 
 --cli-binary-format raw-in-base64-out \ 
invoke-model-output.txt

For more intelligent reasoning capability, you can use Adaptive thinking with Claude Opus 4.7, which lets Claude dynamically allocate thinking token budgets based on the complexity of each request.

To learn more, visit the Anthropic Claude Messages API and check out code examples for multiple use cases and a variety of programming languages.

Things to know
Let me share some important technical details that I think you’ll find useful.

  • Choosing APIs: You can choose from a variety of Bedrock APIs for model inference, as well as the Anthropic Messages API. The Bedrock-native Converse API supports multi-turn conversations and Guardrails integration. The Invoke API provides direct model invocation and lowest-level control.
  • Scaling and capacity: Bedrock’s new inference engine is designed to rapidly provision and serve capacity across many different models. When accepting requests, we prioritize keeping steady state workloads running, and ramp usage and capacity rapidly in response to changes in demand. During periods of high demand, requests are queued, rather than rejected. Up to 10,000 requests per minute (RPM) per account per Region are available immediately, with more available upon request.

Now available
Anthropic’s Claude Opus 4.7 model is available today in the US East (N. Virginia), Asia Pacific (Tokyo), Europe (Ireland), and Europe (Stockholm) Regions; check the full list of Regions for future updates. To learn more, visit the Claude by Anthropic in Amazon Bedrock page and the Amazon Bedrock pricing page.

Give Anthropic’s Claude Opus 4.7 a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

AWS Interconnect is now generally available, with a new option to simplify last-mile connectivity

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-interconnect-is-now-generally-available-with-a-new-option-to-simplify-last-mile-connectivity/

Today, we’re announcing the general availability of AWS Interconnect – multicloud, a managed private connectivity service that connects your Amazon Virtual Private Cloud (Amazon VPC) directly to VPCs on other cloud providers. We’re also introducing AWS Interconnect – last mile, a new capability that simplifies how you establish high-speed, private connections to AWS from your branch offices, data centers, and remote locations through your existing network providers.

Large enterprises increasingly run workloads across multiple cloud providers, whether to use specialized services, meet data residency requirements, or support teams that have standardized on different providers. Connecting those environments reliably and securely has historically required significant coordination: managing VPN tunnels, working with colocation facilities, and configuring third-party network fabrics. The result is that your networking team spends time on undifferentiated heavy lifting instead of focusing on the applications that matter to your business.

AWS Interconnect is the answer to these challenges. It is a managed connectivity service that simplifies connectivity into AWS. Interconnect provides you the ability to establish private, high-speed network connections with dedicated bandwidth to and from AWS across hybrid and multicloud environments. You can configure resilient, end-to-end connectivity with ease in a few clicks through the AWS Console by selecting your location, partner, or cloud provider, preferred Region, and bandwidth requirements, removing the friction of discovering partners and the complexity of manual network configurations.

It comes with two capabilities: multicloud connectivity between AWS and other cloud providers, and last-mile connectivity between AWS and your private on-premises networks. Both capabilities are built on the same principle: a fully managed, turnkey experience that removes the infrastructure complexity from your team.

AWS Interconnect – multicloud
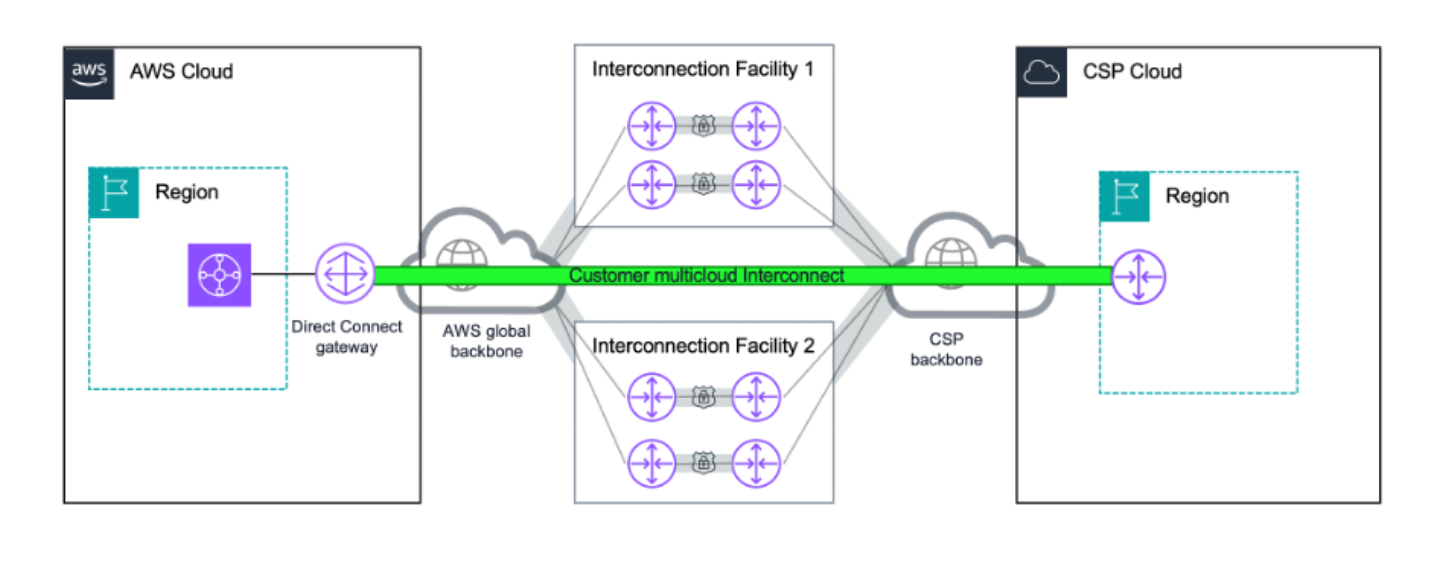
AWS Interconnect – multicloud gives you a private, managed Layer 3 connection between your AWS environment and other cloud providers, starting with Google Cloud, and Microsoft Azure coming later in 2026. Traffic flows entirely over the AWS global backbone and the partner cloud’s private network, so it never traverses the public internet. This means you get predictable latency, consistent throughput, and isolation from internet congestion without having to manage any physical infrastructure yourself.

Security is built in by default. Every connection uses IEEE 802.1AE MACsec encryption on the physical links between AWS routers and the partner cloud provider’s routers at the interconnection facilities. You don’t need to configure these separately. Note that each cloud provider manages encryption independently on its own backbone, so you should review the encryption documentation for your specific deployment to verify it meets your compliance requirements. Resiliency is also built in: each connection spans multiple logical links distributed across at least two physical facilities, so a single device or building failure does not interrupt your connectivity.

AWS Interconnect - multicloud - architectureFor monitoring, AWS Interconnect – multicloud integrates with Amazon CloudWatch. You get a Network Synthetic Monitor included with each connection to track round-trip latency and packet loss, and bandwidth utilization metrics to support capacity planning.

AWS has published the underlying specification on GitHub under the Apache 2.0 license, providing any cloud service provider the opportunity to collaborate with AWS Interconnect – multicloud. To become an AWS Interconnect partner, cloud providers must implement the technical specification and meet AWS operational requirements, including resiliency standards, support commitments, and service level agreements.

How it works
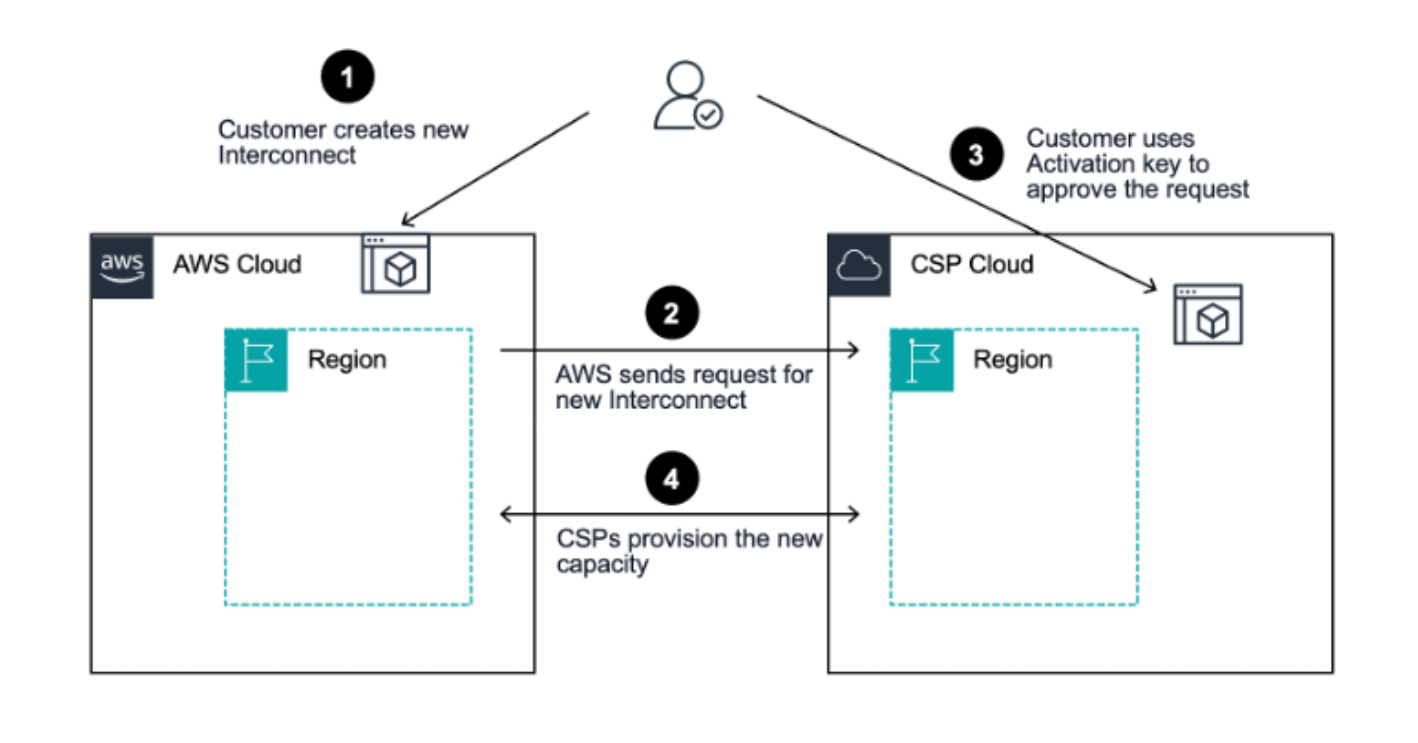
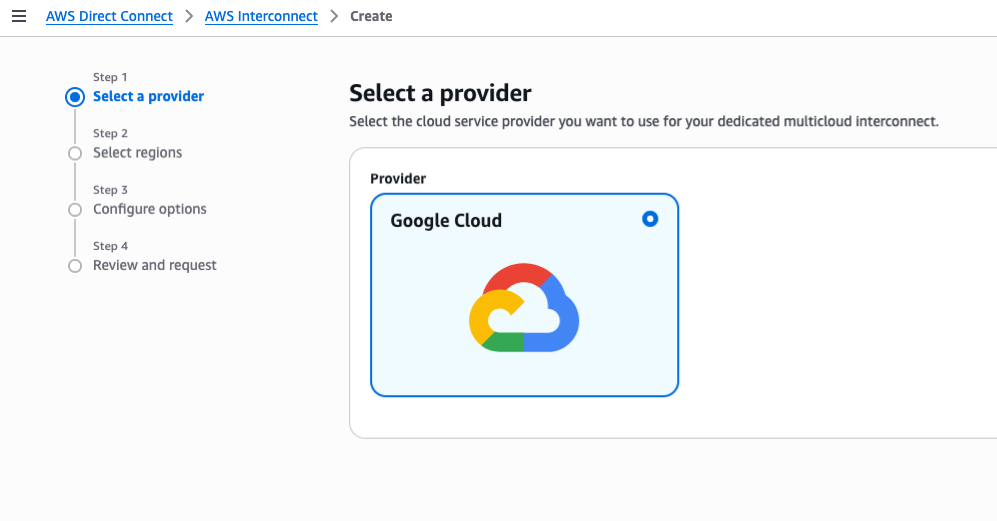
Provisioning a connection takes minutes. I create the connection from the AWS Direct Connect console. I start from the AWS Interconnect section and select Google Cloud as the provider. I select my source and destination regions. I specify bandwidth, and provide my Google Cloud project ID. AWS generates an activation key that I use on the Google Cloud side to complete the connection. Routes propagate automatically in both directions, and my workloads can start exchanging data shortly after.

AWS INterconnect - multicloud - provisionningFor this demo, I start with a single VPC and I connect it to a Google Cloud VPC. I use a Direct Connect Gateway. It’s the simplest path: one connection, one attachment, and my workloads on both sides can start talking to each other in minutes.

Step 1: request an interconnect in the AWS Management Console.

I navigate to AWS Direct Connect, AWS Interconnect and I select Create. I first choose the cloud provider I want to connect to. In this example, Google Cloud.

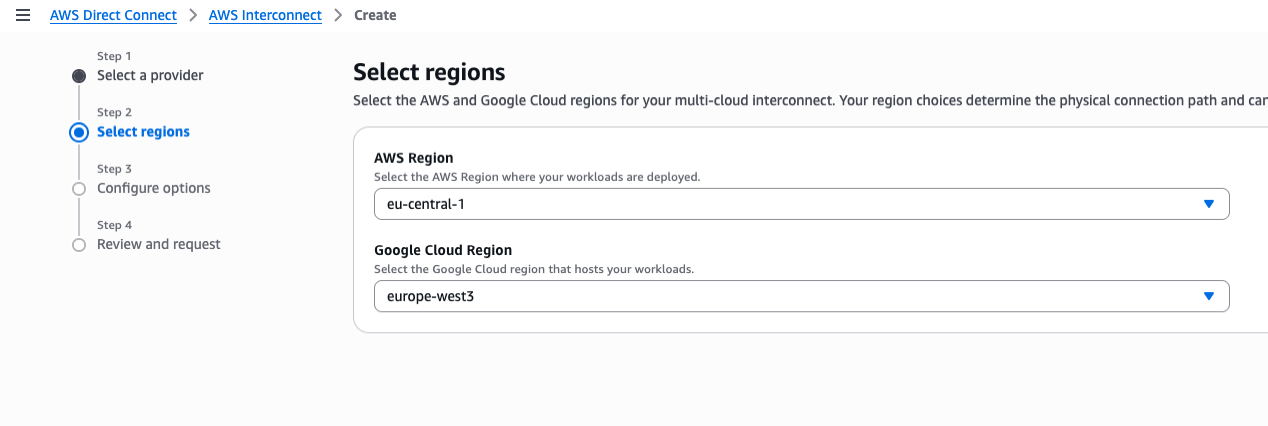
AWS interconnect - 1Then, I choose the AWS Region (eu-central-1) and the Google Cloud Region (europe-west3).

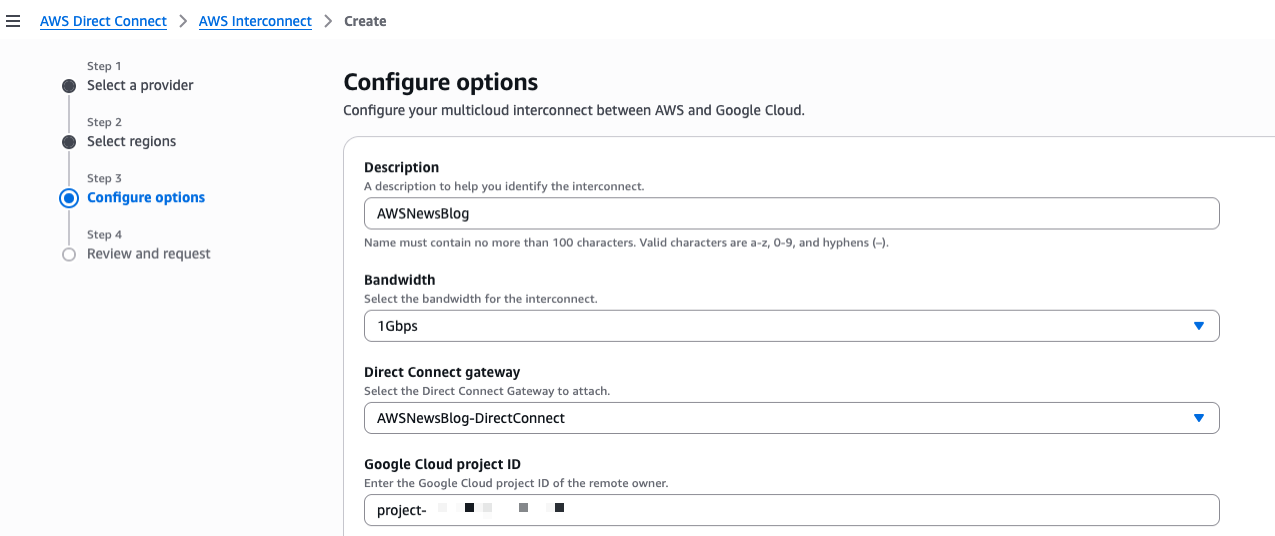
AWS interconnect - 2On step 3, I enter Description,I choose the Bandwidth, the Direct Connect gateway to attach, and the ID of my Google Cloud project.

AWS interconnect - 3

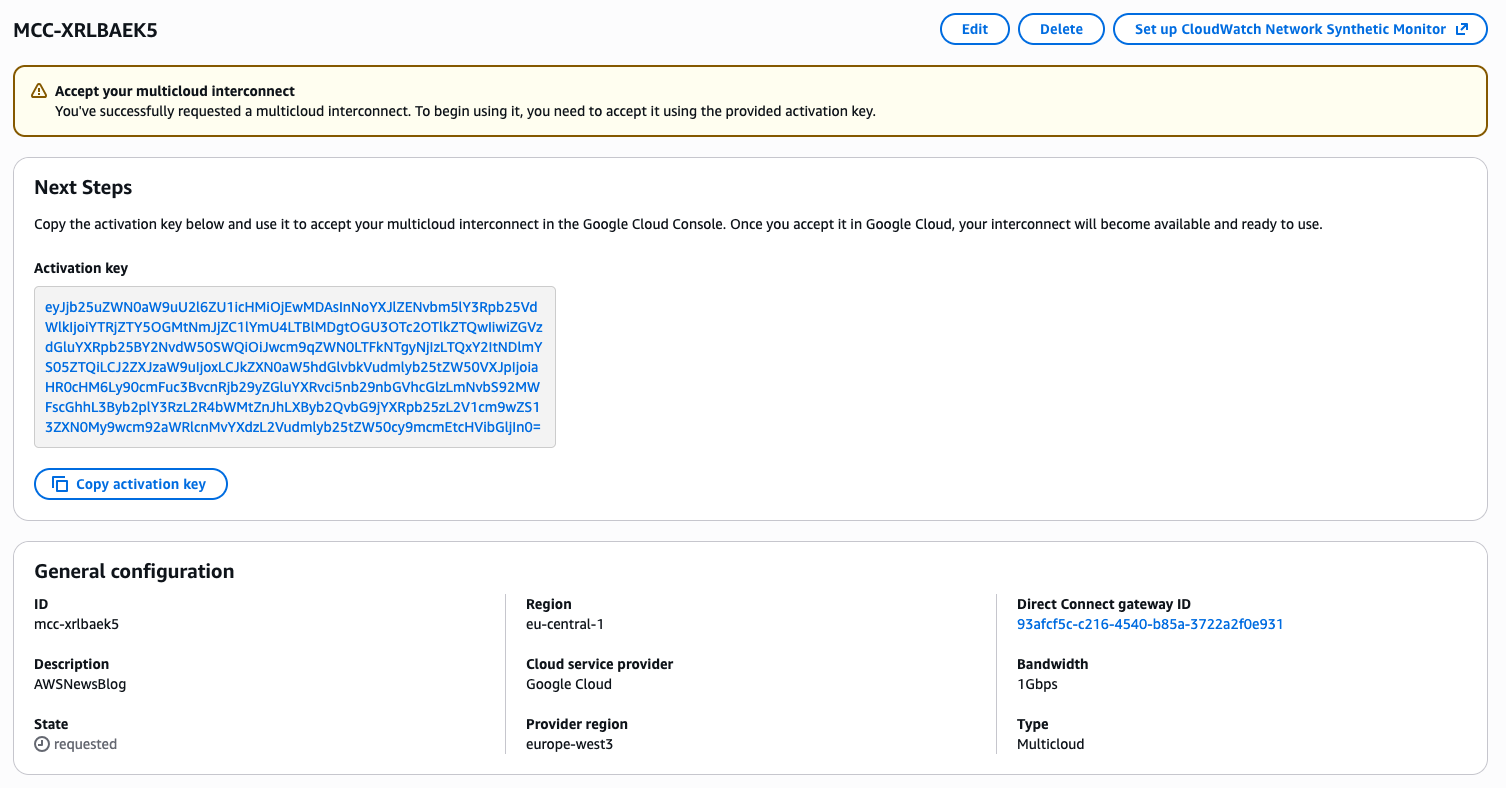
After reviewing and confirming the request, the console gives me an activation key. I will use that key to validate the request on the Google cloud side.

AWS interconnect - 4

Step 2: create the transport and VPC Peering resources on my Google Cloud Platform (GCP) account.

Now that I have the activation key, I continue the process on the GCP side. At the time of this writing, no web-based console was available. I choose to use the GCP command line (CLI) instead. I take note of the CIDR range in the GCP VPC subnet in the europe-west3 region. Then, I open a Terminal and type:

gcloud network-connectivity transports create aws-news-blog \
    --region=europe-west3  \
    --activation-key=${ACTIVATION_KEY} \
    --network=default \
    --advertised-routes=10.156.0.0/20

Create request issued for: [aws-news-blog]
...
peeringNetwork: projects/oxxxp-tp/global/networks/transport-9xxxf-vpc
...
state: PENDING_CONFIG
updateTime: '2026-03-19T09:30:51.103979219Z'

It takes a couple of minutes for the command to complete. Once the command returns, I create a peering between my GCP VPC and the new transport I just created. I can do that in the GCP console or with the gcloud command line. Because I was using the Terminal for the previous command, I continued with the command line:

gcloud compute networks peerings create aws-news-blog \
      --network=default \
      --peer-network=projects/oxxxp-tp/global/networks/transport-9xxxf-vpc \
      --import-custom-routes \
      --export-custom-routes

The network name is the name of my GCP VPC. The peer network is given in the output of the previous command.

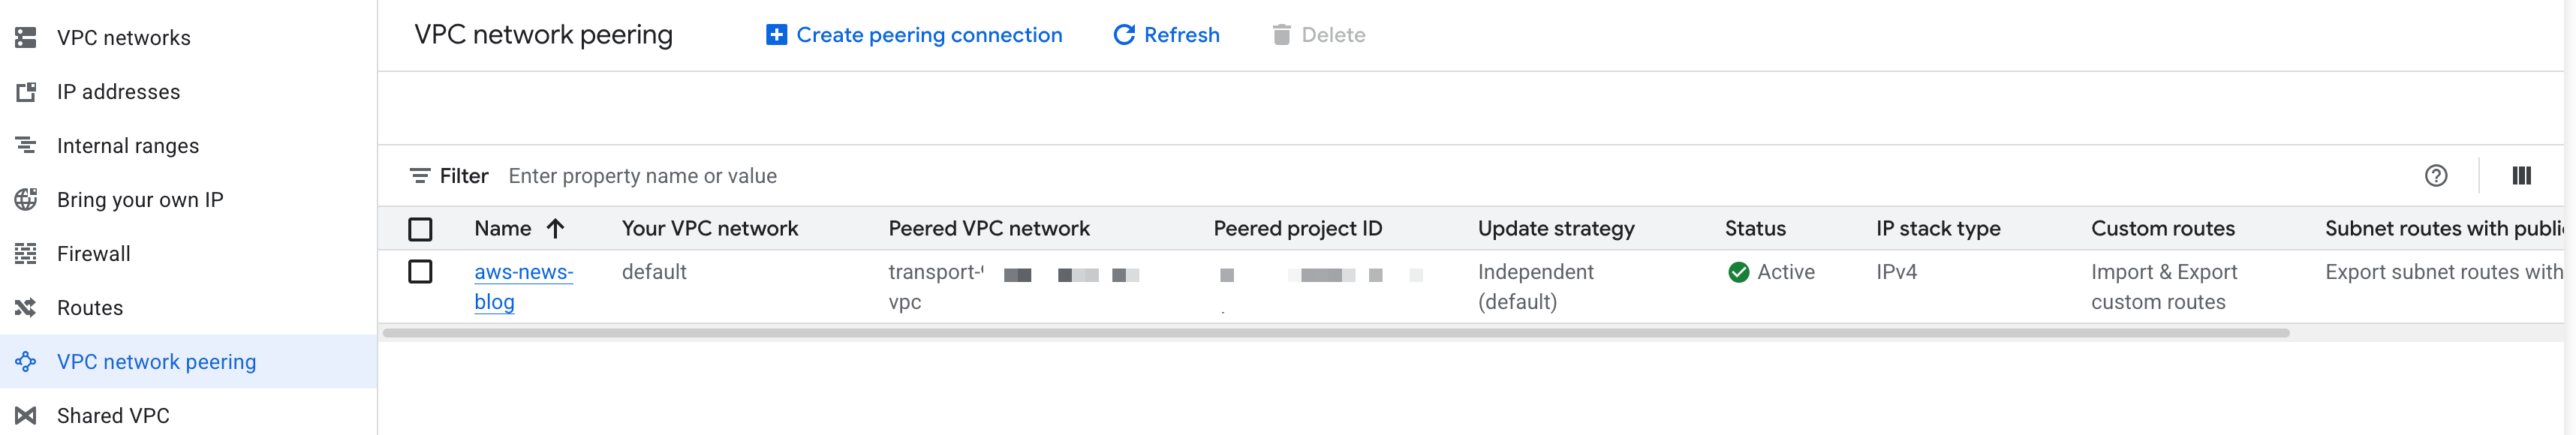
Once completed, I can verify the peering in the GCP console.
AWS Interconnect - Peering in the Google console

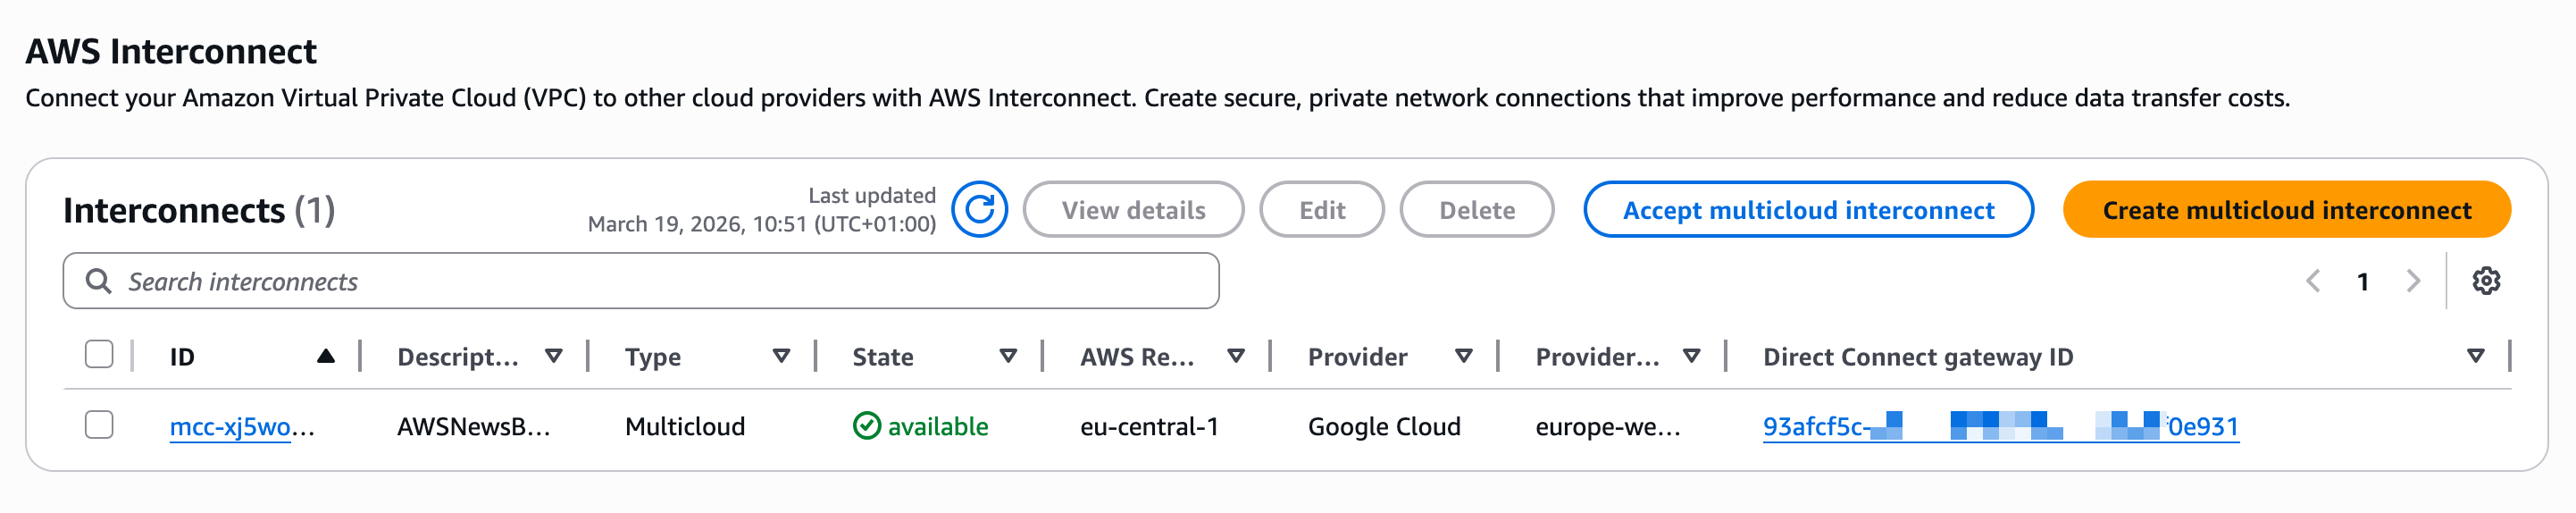
In the AWS Interconnect console, I verify the status is available.

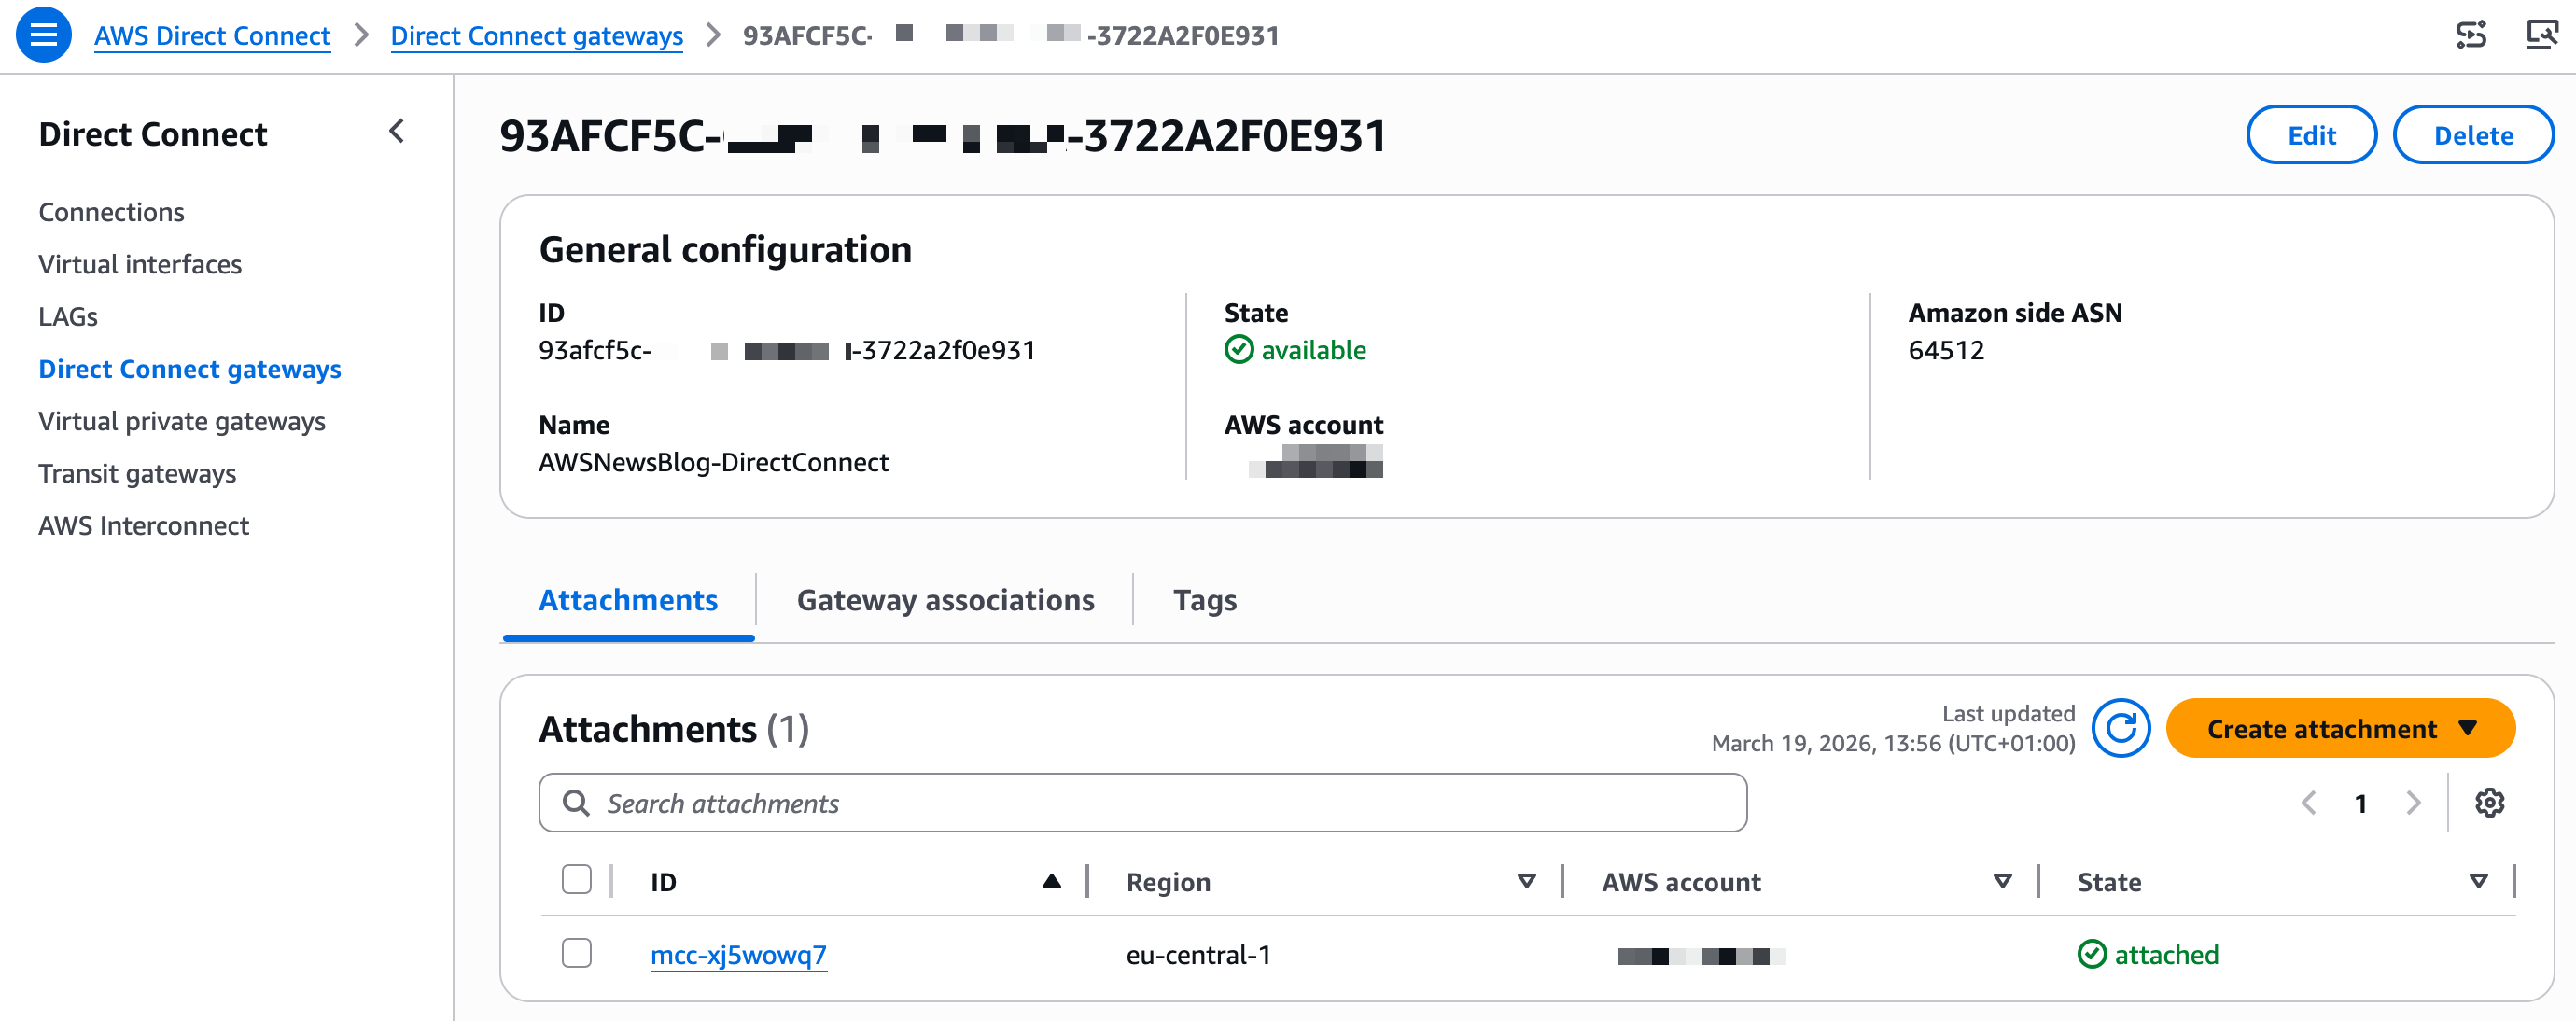
AWS Interconnect availableIn the AWS Direct Connect console, under Direct Connect gateways, I see the attachment to the new interconnect.

AWS INterconnect attachment

Step 3: associate the new gateway on the AWS side

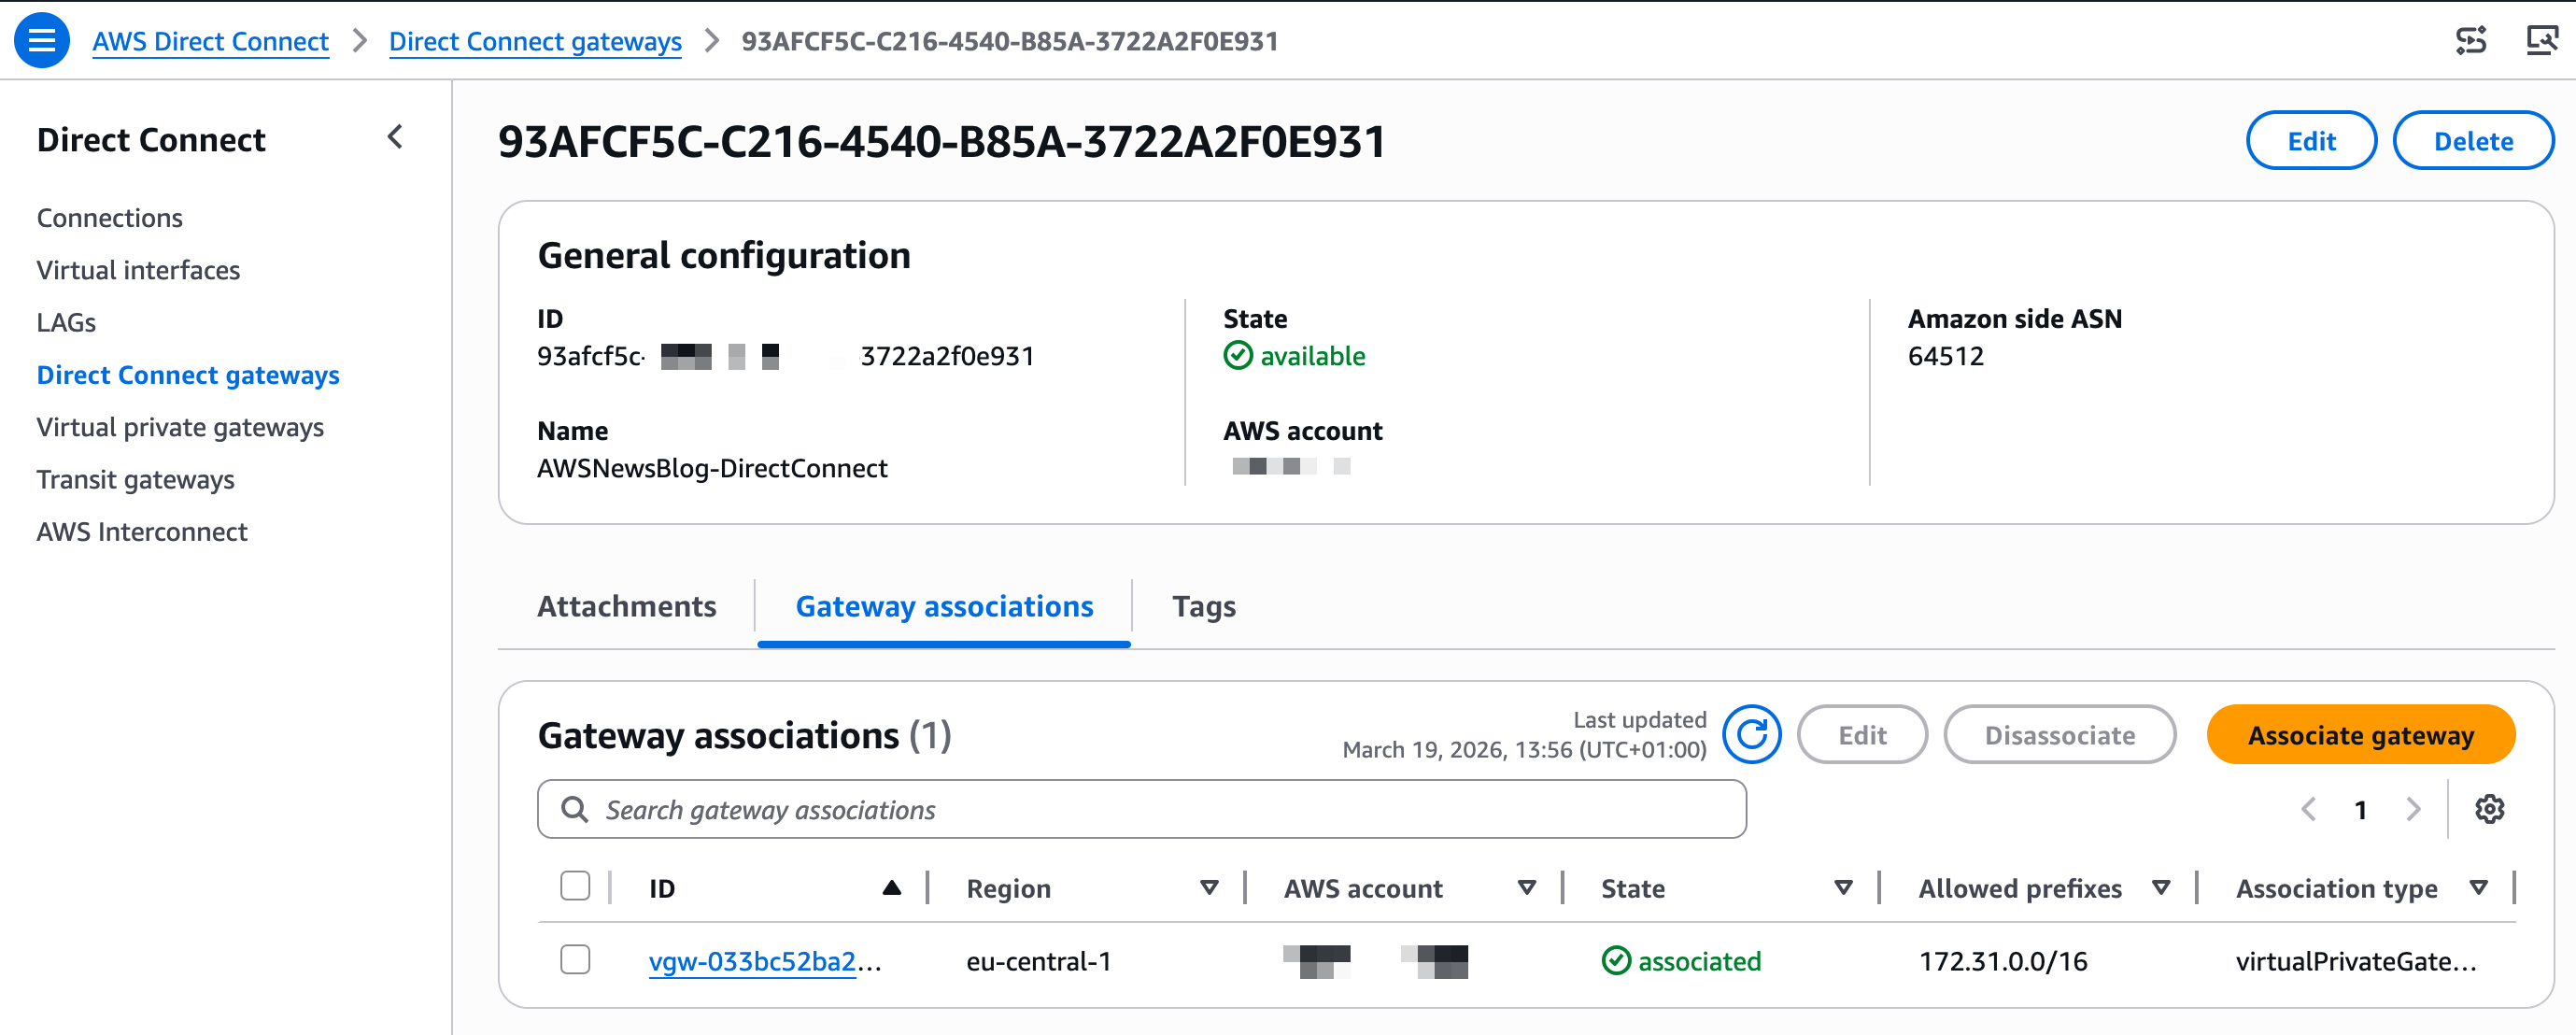
I select Gateway associations and Associate gateway to attach the Virtual Private Gateway (VGW) that I created before starting this demo (pay attention to use a VGW in the same AWS Region as the interconnect)

AWS Interconnect associate CGW

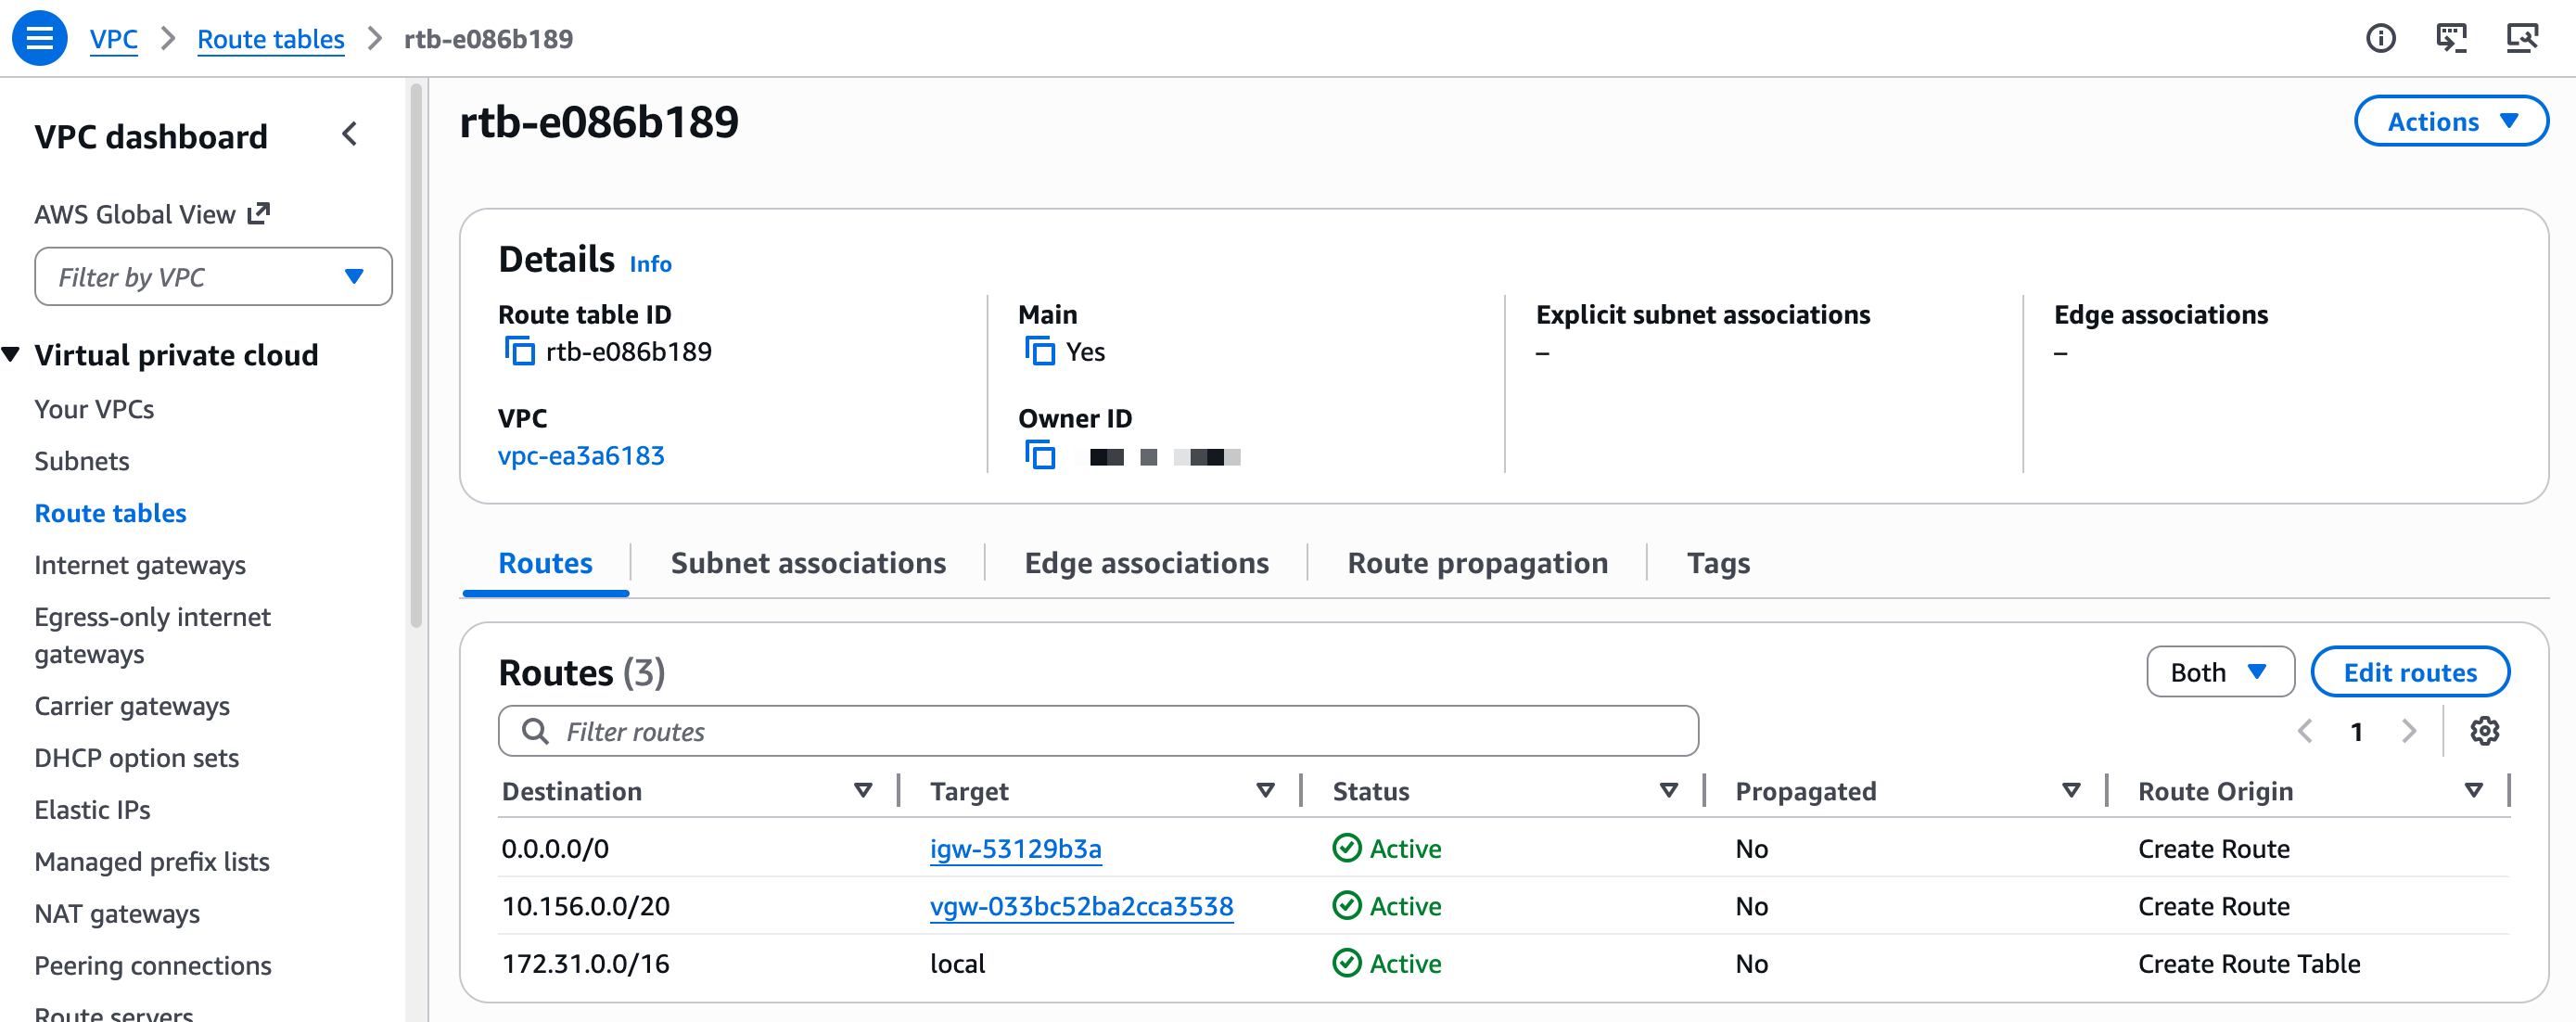
You don’t need to configure the network routing on the GCP side. On AWS, there is a final step: add a route entry in your VPC Route tables to send all traffic to the GCP IP address range through the Virtual Gateway.

VPC Route to the VGW

Once the network setup is done. I start two compute instances, one on AWS and one on GCP.

On AWS, I verify the Security Group accepts ingress traffic on TCP:8080. I connect to the machine and I start a minimal web server:

python3 -c \
"from http.server import HTTPServer, BaseHTTPRequestHandler 
class H(BaseHTTPRequestHandler):
   def do_GET(self):
      self.send_response(200);self.end_headers()
      self.wfile.write(b'Hello AWS World!\n\n')
HTTPServer(('',8080),H).serve_forever()"

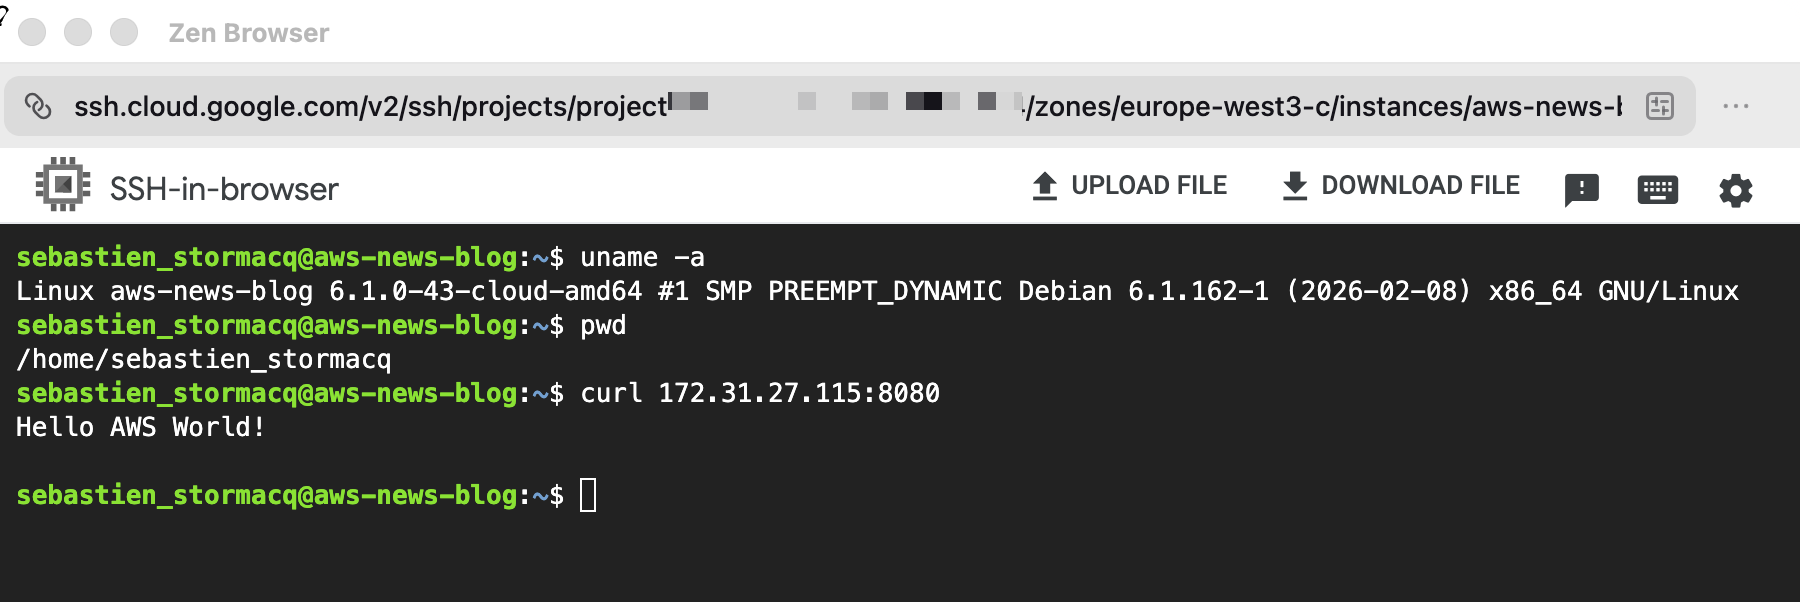
On the GCP side, I open a SSH session to the machine and I call the AWS web server by its private IP address.

AWS Interconnect : curl from GCP to AWS

Et voilà! I have a private network route between my two networks, entirely managed by the two Cloud Service Providers.

Things to know
There are a couple of configuration options that you should keep in mind:

  • When connecting networks, pay attention to the IP addresses range on both sides. The GCP and AWS VPC ranges can’t overlap. For this demo, the default range on AWS was 172.31.0.0/16and the default on GCP was 10.156.0.0/20. I was able to proceed with these default values.
  • You can configure IPV4, IPV6, or both on each side. You must select the same option on both sides.
  • The Maximum Transmission Unit (MTU) must be the same on both VPC. The default values for AWS VPCs and GCP VPCs are not. MTU is the largest packet size, in bytes, that a network interface can transmit without fragmentation. Mismatched MTU sizes between peered VPCs cause packet drops or fragmentation, leading to silent data loss, degraded throughput, and broken connections across the interconnect.
  • For more details, refer to the GCP Partner Cross Cloud Interconnect and the AWS Interconnect User Guide.

Reference architectures
When your deployment grows and you have multiple VPCs in a single region, AWS Transit Gateway gives you a centralized routing hub to connect them all through a single Interconnect attachment. You can segment traffic between environments, apply consistent routing policies, and integrate AWS Network Firewall if you need to inspect what crosses the cloud boundary.

And when you’re operating at global scale, with workloads spread across multiple AWS Regions and multiple Google Cloud environments, AWS Cloud WAN extends that same model across the world. Any region in your network can reach any Interconnect attachment globally, with centralized policy management and segment-based routing that applies consistently everywhere you operate.

My colleagues Alexandra and Santiago documented these reference architectures in their blog post: Build resilient and scalable multicloud connectivity architectures with AWS Interconnect – multicloud.

AWS Interconnect – last mile
Based on the same architecture and design as AWS Interconnect – multicloud, AWS Interconnect – last mile provides the ability to connect your on-premises or remote location to AWS through a participating network provider’s last-mile infrastructure, directly from the AWS Management Console.

The onboarding process mirrors AWS Interconnect – multicloud: you select a provider, authenticate, and specify your connection endpoints and bandwidth. AWS generates an activation key that you provide in the provider console to complete the configuration. AWS Interconnect – last mile automatically provisions four redundant connections across two physical locations, configures BGP routing, and activates MACsec encryption and Jumbo Frames by default. The result is a resilient private connection to AWS that aligns with best practices, without requiring you to manually configure networking components.

AWS Interconnect - lastmile

AWS Interconnect – last mile supports bandwidths from 1 Gbps to 100 Gbps, and you can adjust bandwidth from the console without reprovisioning. The service includes a 99.99% availability SLA up to the Direct Connect port and bundles CloudWatch Network Synthetic Monitor for connection health monitoring. Just like AWS Interconnect – multicloud, AWS Interconnect – last mile attaches to a Direct Connect Gateway, which connects to your Virtual Private Gateway, Transit Gateway, or AWS Cloud WAN deployment. For more details, refer to the AWS Interconnect User Guide.

Scott Yow, SVP Product at Lumen Technologies, wrote:

By combining AWS Interconnect – last mile with Lumen fiber network and Cloud Interconnect, we simplify the last-mile complexity that often slows cloud adoption and enable a faster, and more resilient path to AWS for customers.

Pricing and availability
AWS Interconnect – multicloud and AWS Interconnect – last mile pricing is based on a flat hourly rate for the capacity you request, billed prorata by the hour. You select the bandwidth tier that fits your workload needs.

AWS Interconnect – multicloud pricing varies by region pair: a connection between US East (N. Virginia) and Google Cloud N. Virginia is priced differently from a connection between US East (N. Virginia) and a more distant region. When you use AWS Cloud WAN, the global any-to-any routing model means traffic can traverse multiple regions, which affects the total cost of your deployment. I recommend reviewing the AWS Interconnect pricing page for the full rate card by region pair and capacity tier before sizing your connection.

AWS Interconnect – multicloud is available today in five region pairs: US East (N. Virginia) to Google Cloud N. Virginia, US West (N. California) to Google Cloud Los Angeles, US West (Oregon) to Google Cloud Oregon, Europe (London) to Google Cloud London, and Europe (Frankfurt) to Google Cloud Frankfurt. Microsoft Azure support is coming later in 2026.

AWS Interconnect – last mile is launching in US East (N. Virginia) with Lumen as the initial partner. Additional partners, including AT&T and Megaport, are in progress, and additional regions are planned.

To get started with AWS Interconnect, visit the AWS Direct Connect console and select AWS Interconnect from the navigation menu.

I’d love to hear how you’re using AWS Interconnect in your environment. Leave a comment below or reach out through the AWS re:Post community.

— seb
Launching S3 Files, making S3 buckets accessible as file systems

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/launching-s3-files-making-s3-buckets-accessible-as-file-systems/

I’m excited to announce Amazon S3 Files, a new file system that seamlessly connects any AWS compute resource with Amazon Simple Storage Service (Amazon S3).

More than a decade ago, as an AWS trainer, I spent countless hours explaining the fundamental differences between object storage and file systems. My favorite analogy was comparing S3 objects to books in a library (you can’t edit a page, you need to replace the whole book) versus files on your computer that you can modify page by page. I drew diagrams, created metaphors, and helped customers understand why they needed different storage types for different workloads. Well, today that distinction becomes a bit more flexible.

With S3 Files, Amazon S3 is the first and only cloud object store that offers fully-featured, high-performance file system access to your data. It makes your buckets accessible as file systems. This means changes to data on the file system are automatically reflected in the S3 bucket and you have fine-grained control over synchronization. S3 Files can be attached to multiple compute resources enabling data sharing across clusters without duplication.

Until now, you had to choose between Amazon S3 cost, durability, and the services that can natively consume data from it or a file system’s interactive capabilities. S3 Files eliminates that tradeoff. S3 becomes the central hub for all your organization’s data. It’s accessible directly from any AWS compute instance, container, or function, whether you’re running production applications, training ML models, or building agentic AI systems.

You can access any general purpose bucket as a native file system on your Amazon Elastic Compute Cloud (Amazon EC2) instances, containers running on Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service (Amazon EKS), or AWS Lambda functions. The file system presents S3 objects as files and directories, supporting all Network File System (NFS) v4.1+ operations like creating, reading, updating, and deleting files.

As you work with specific files and directories through the file system, associated file metadata and contents are placed onto the file system’s high-performance storage. By default, files that benefit from low-latency access are stored and served from the high performance storage. For files not stored on high performance storage such as those needing large sequential reads, S3 Files automatically serves those files directly from Amazon S3 to maximize throughput. For byte-range reads, only the requested bytes are transferred, minimizing data movement and costs.

The system also supports intelligent pre-fetching to anticipate your data access needs. You also have fine-grained control over what gets stored on the file system’s high performance storage. You can decide whether to load full file data or metadata only, which means you can optimize for your specific access patterns.

Under the hood, S3 Files uses Amazon Elastic File System (Amazon EFS) and delivers ~1ms latencies for active data. The file system supports concurrent access from multiple compute resources with NFS close-to-open consistency, making it ideal for interactive, shared workloads that mutate data, from agentic AI agents collaborating through file-based tools to ML training pipelines processing datasets.

Let me show you how to get started.
Creating my first Amazon S3 file system, mounting, and using it from an EC2 instance is straightforward.

I have an EC2 instance and a general purpose bucket. In this demo, I configure an S3 file system and access the bucket from an EC2 instance, using regular file system commands.

For this demo, I use the AWS Management Console. You can also use the AWS Command Line Interface (AWS CLI) or infrastructure as code (IaC).

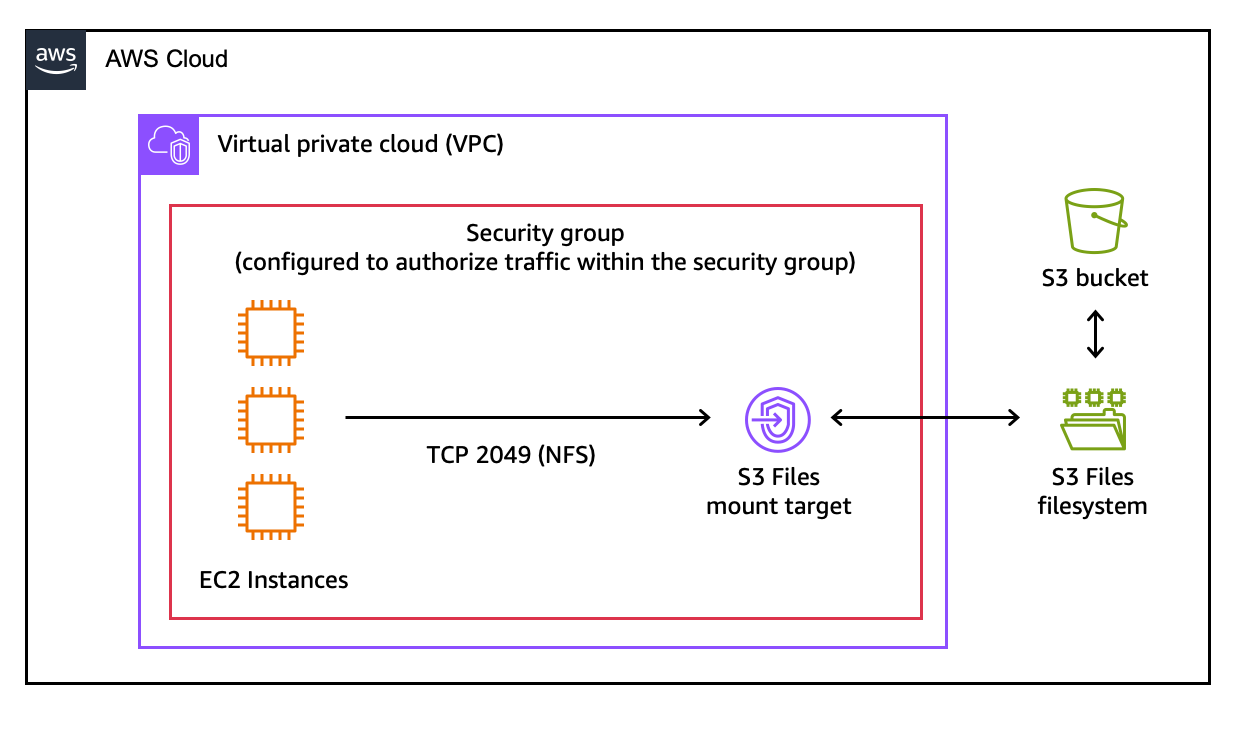
Here is the architecture diagram for this demo.

S3 Files demo architectureStep 1: Create an S3 file system.

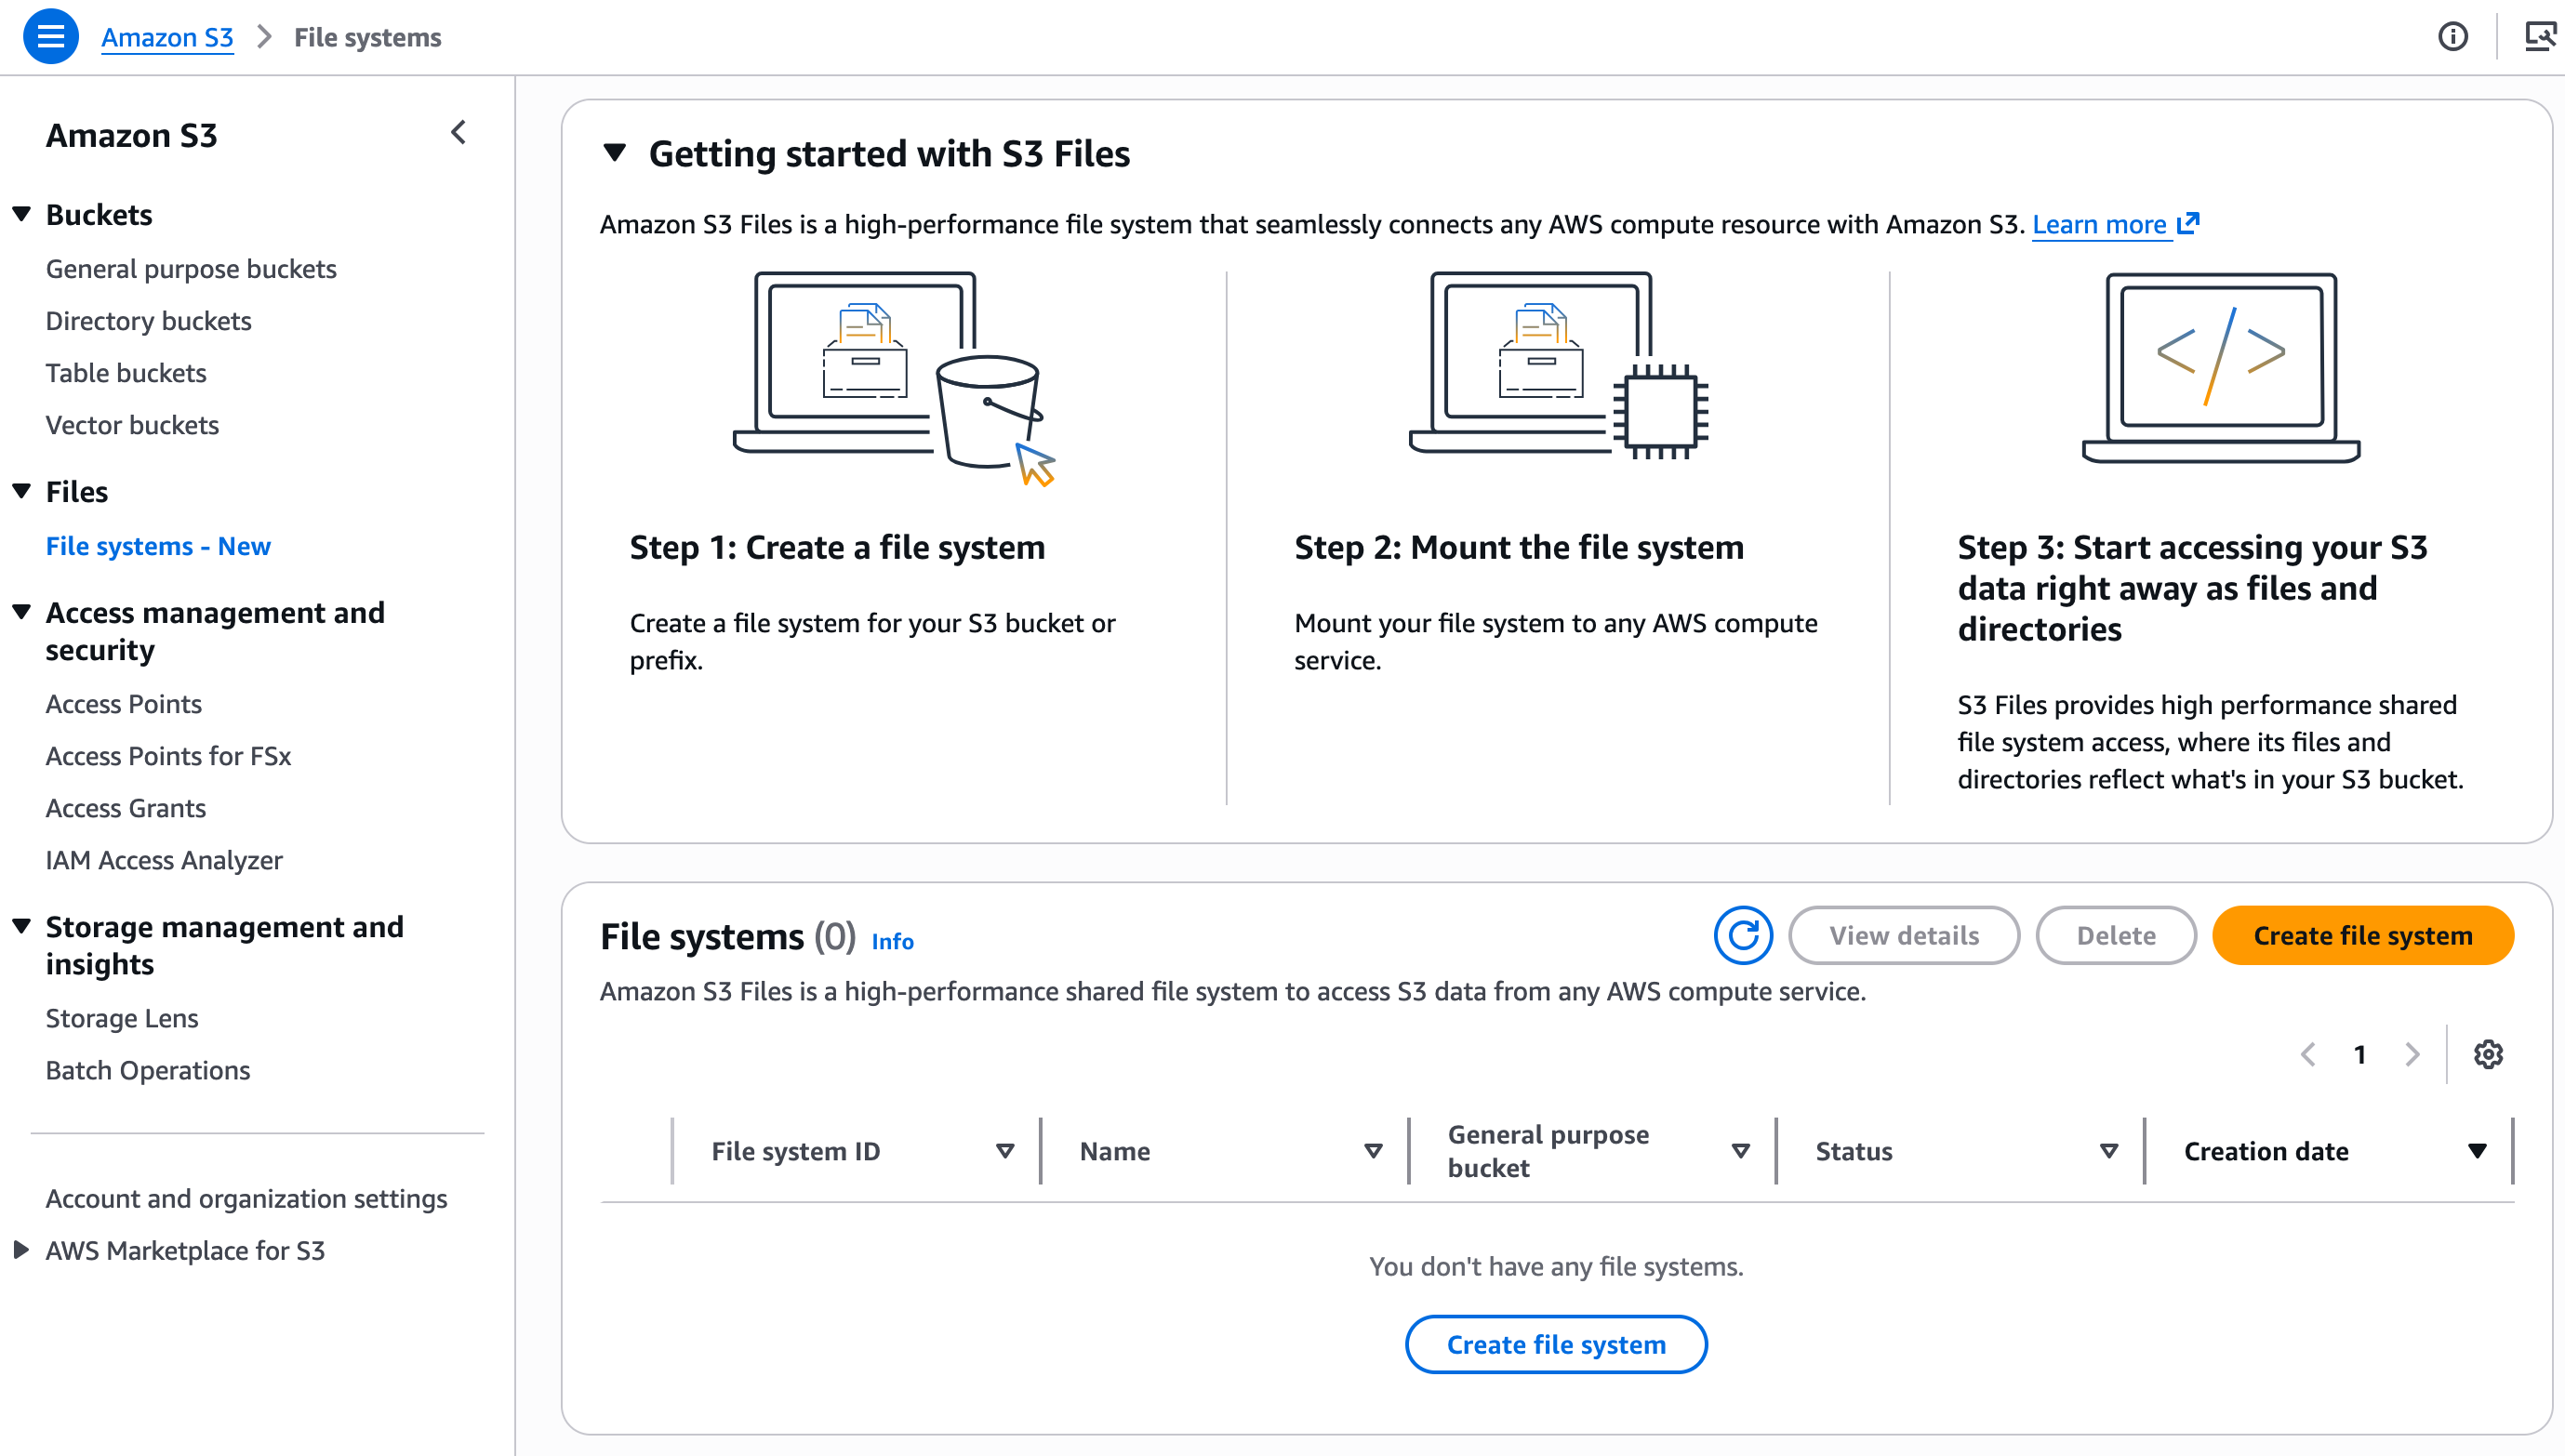
On the Amazon S3 section of the console, I choose File systems and then Create file system.

S3 Files create file system

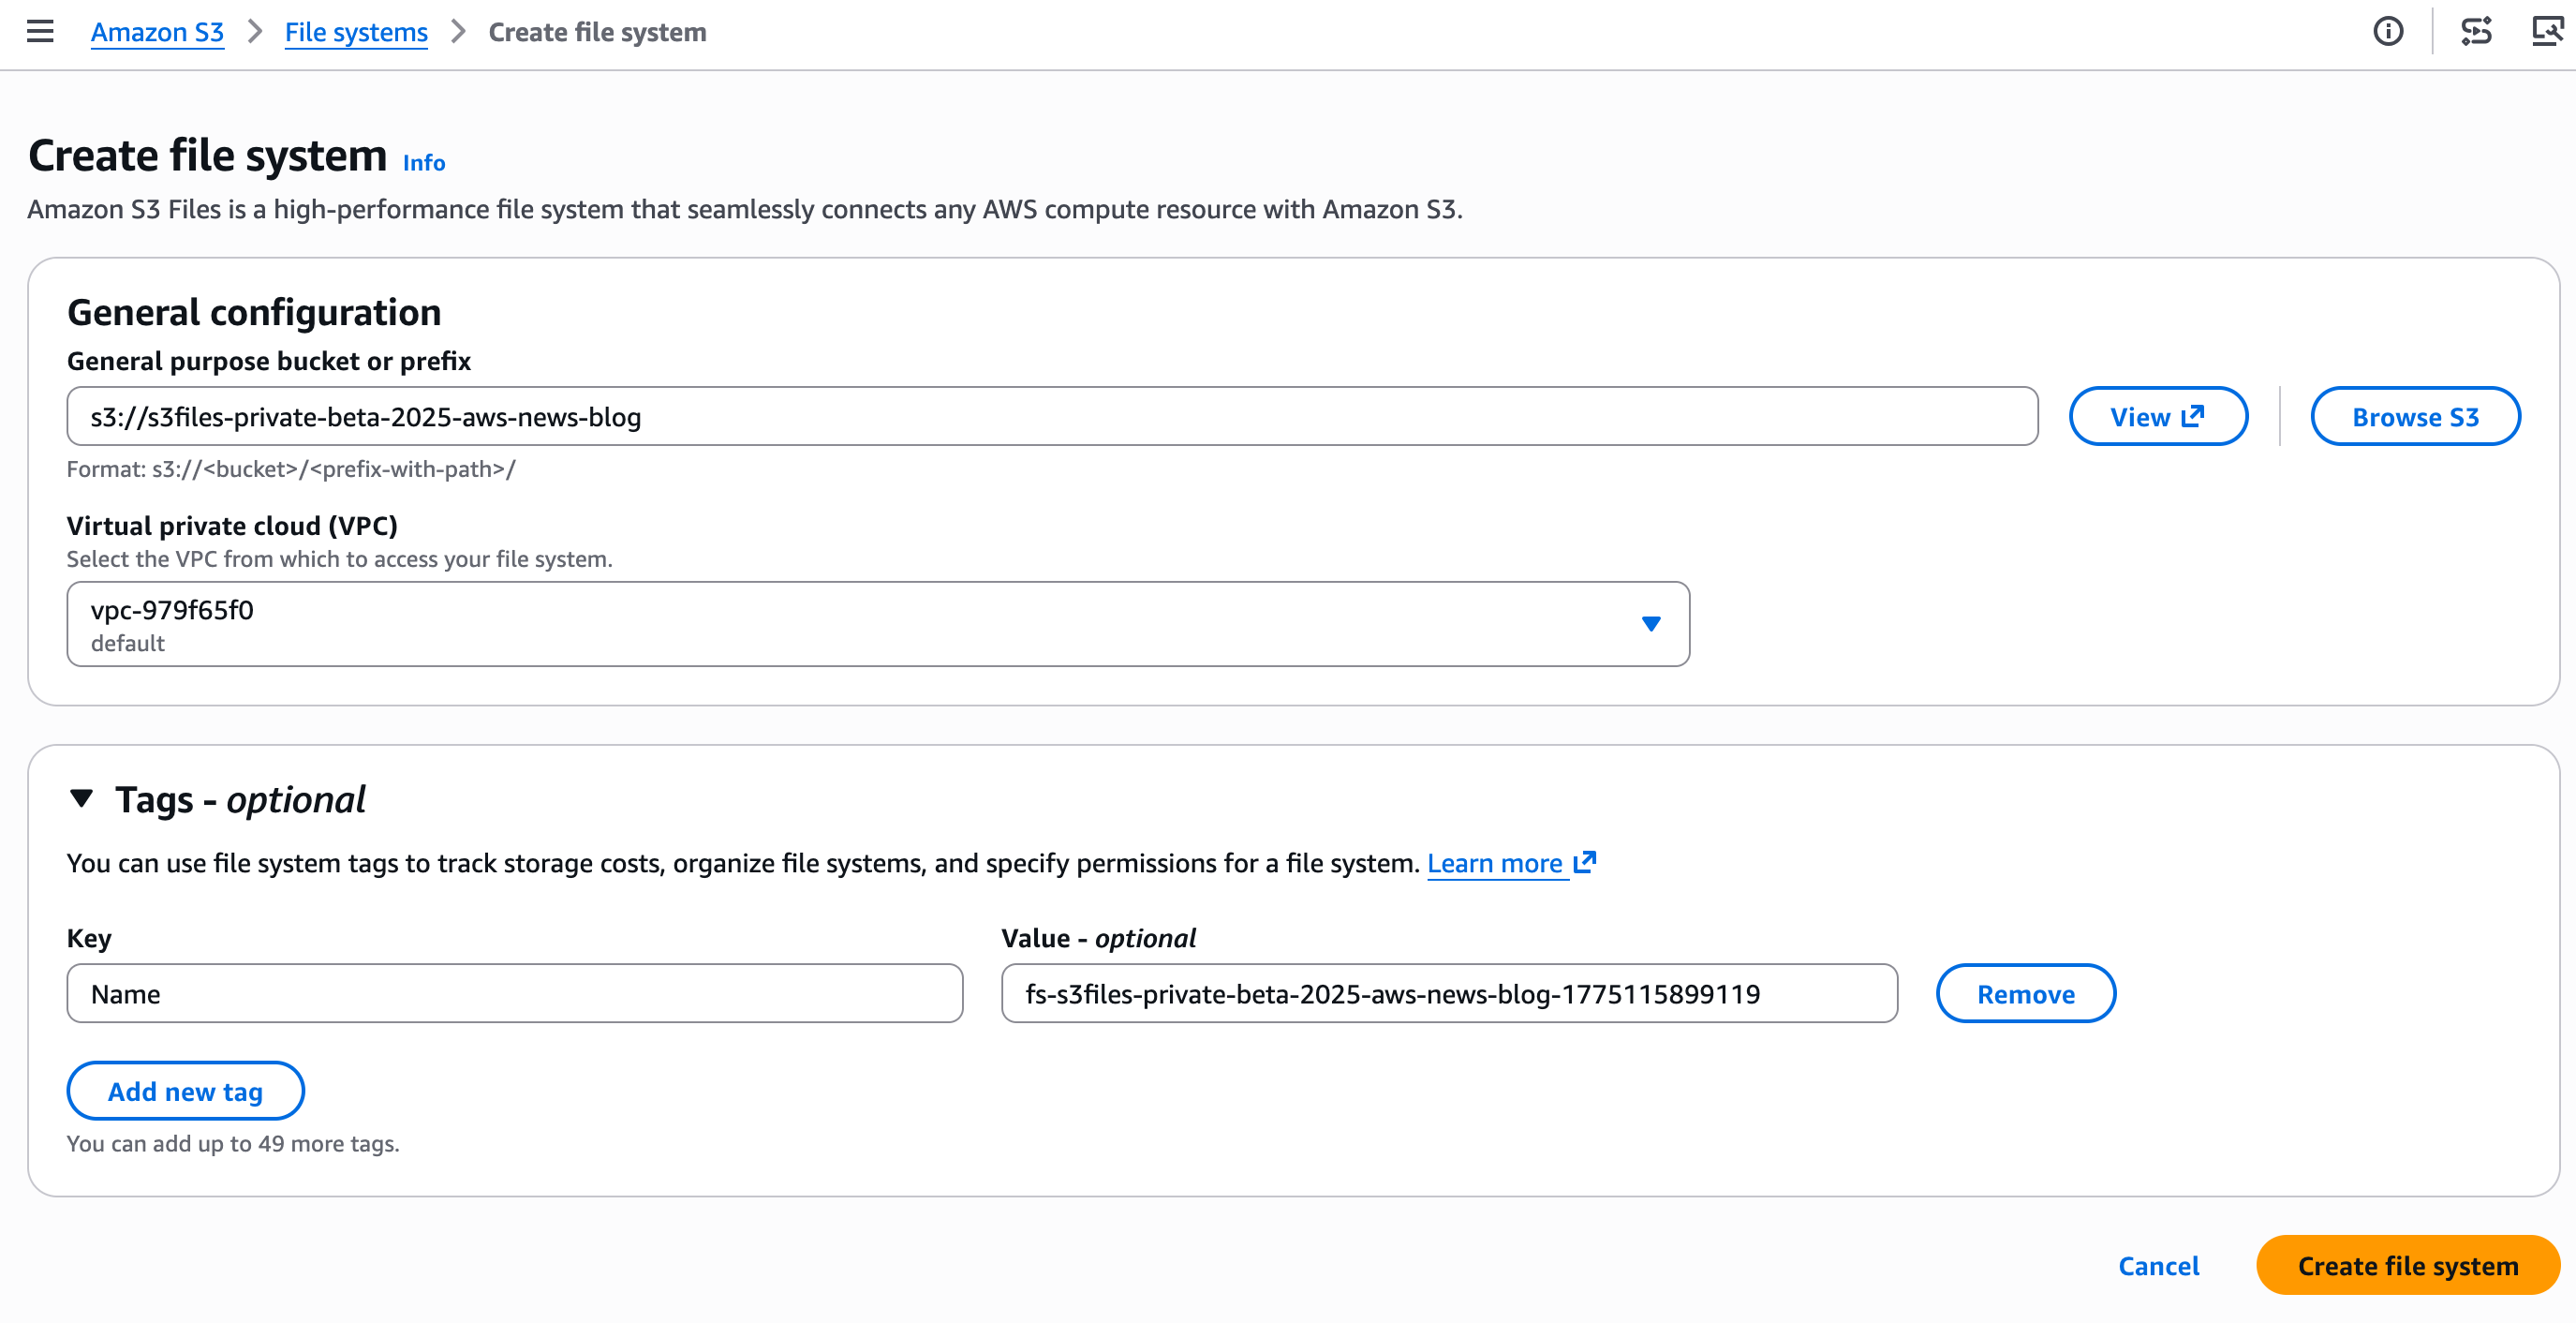
I enter the name of the bucket I want to expose as a file system and choose Create file system.

S3 Files create file system, part 2

Step 2: Discover the mount target.

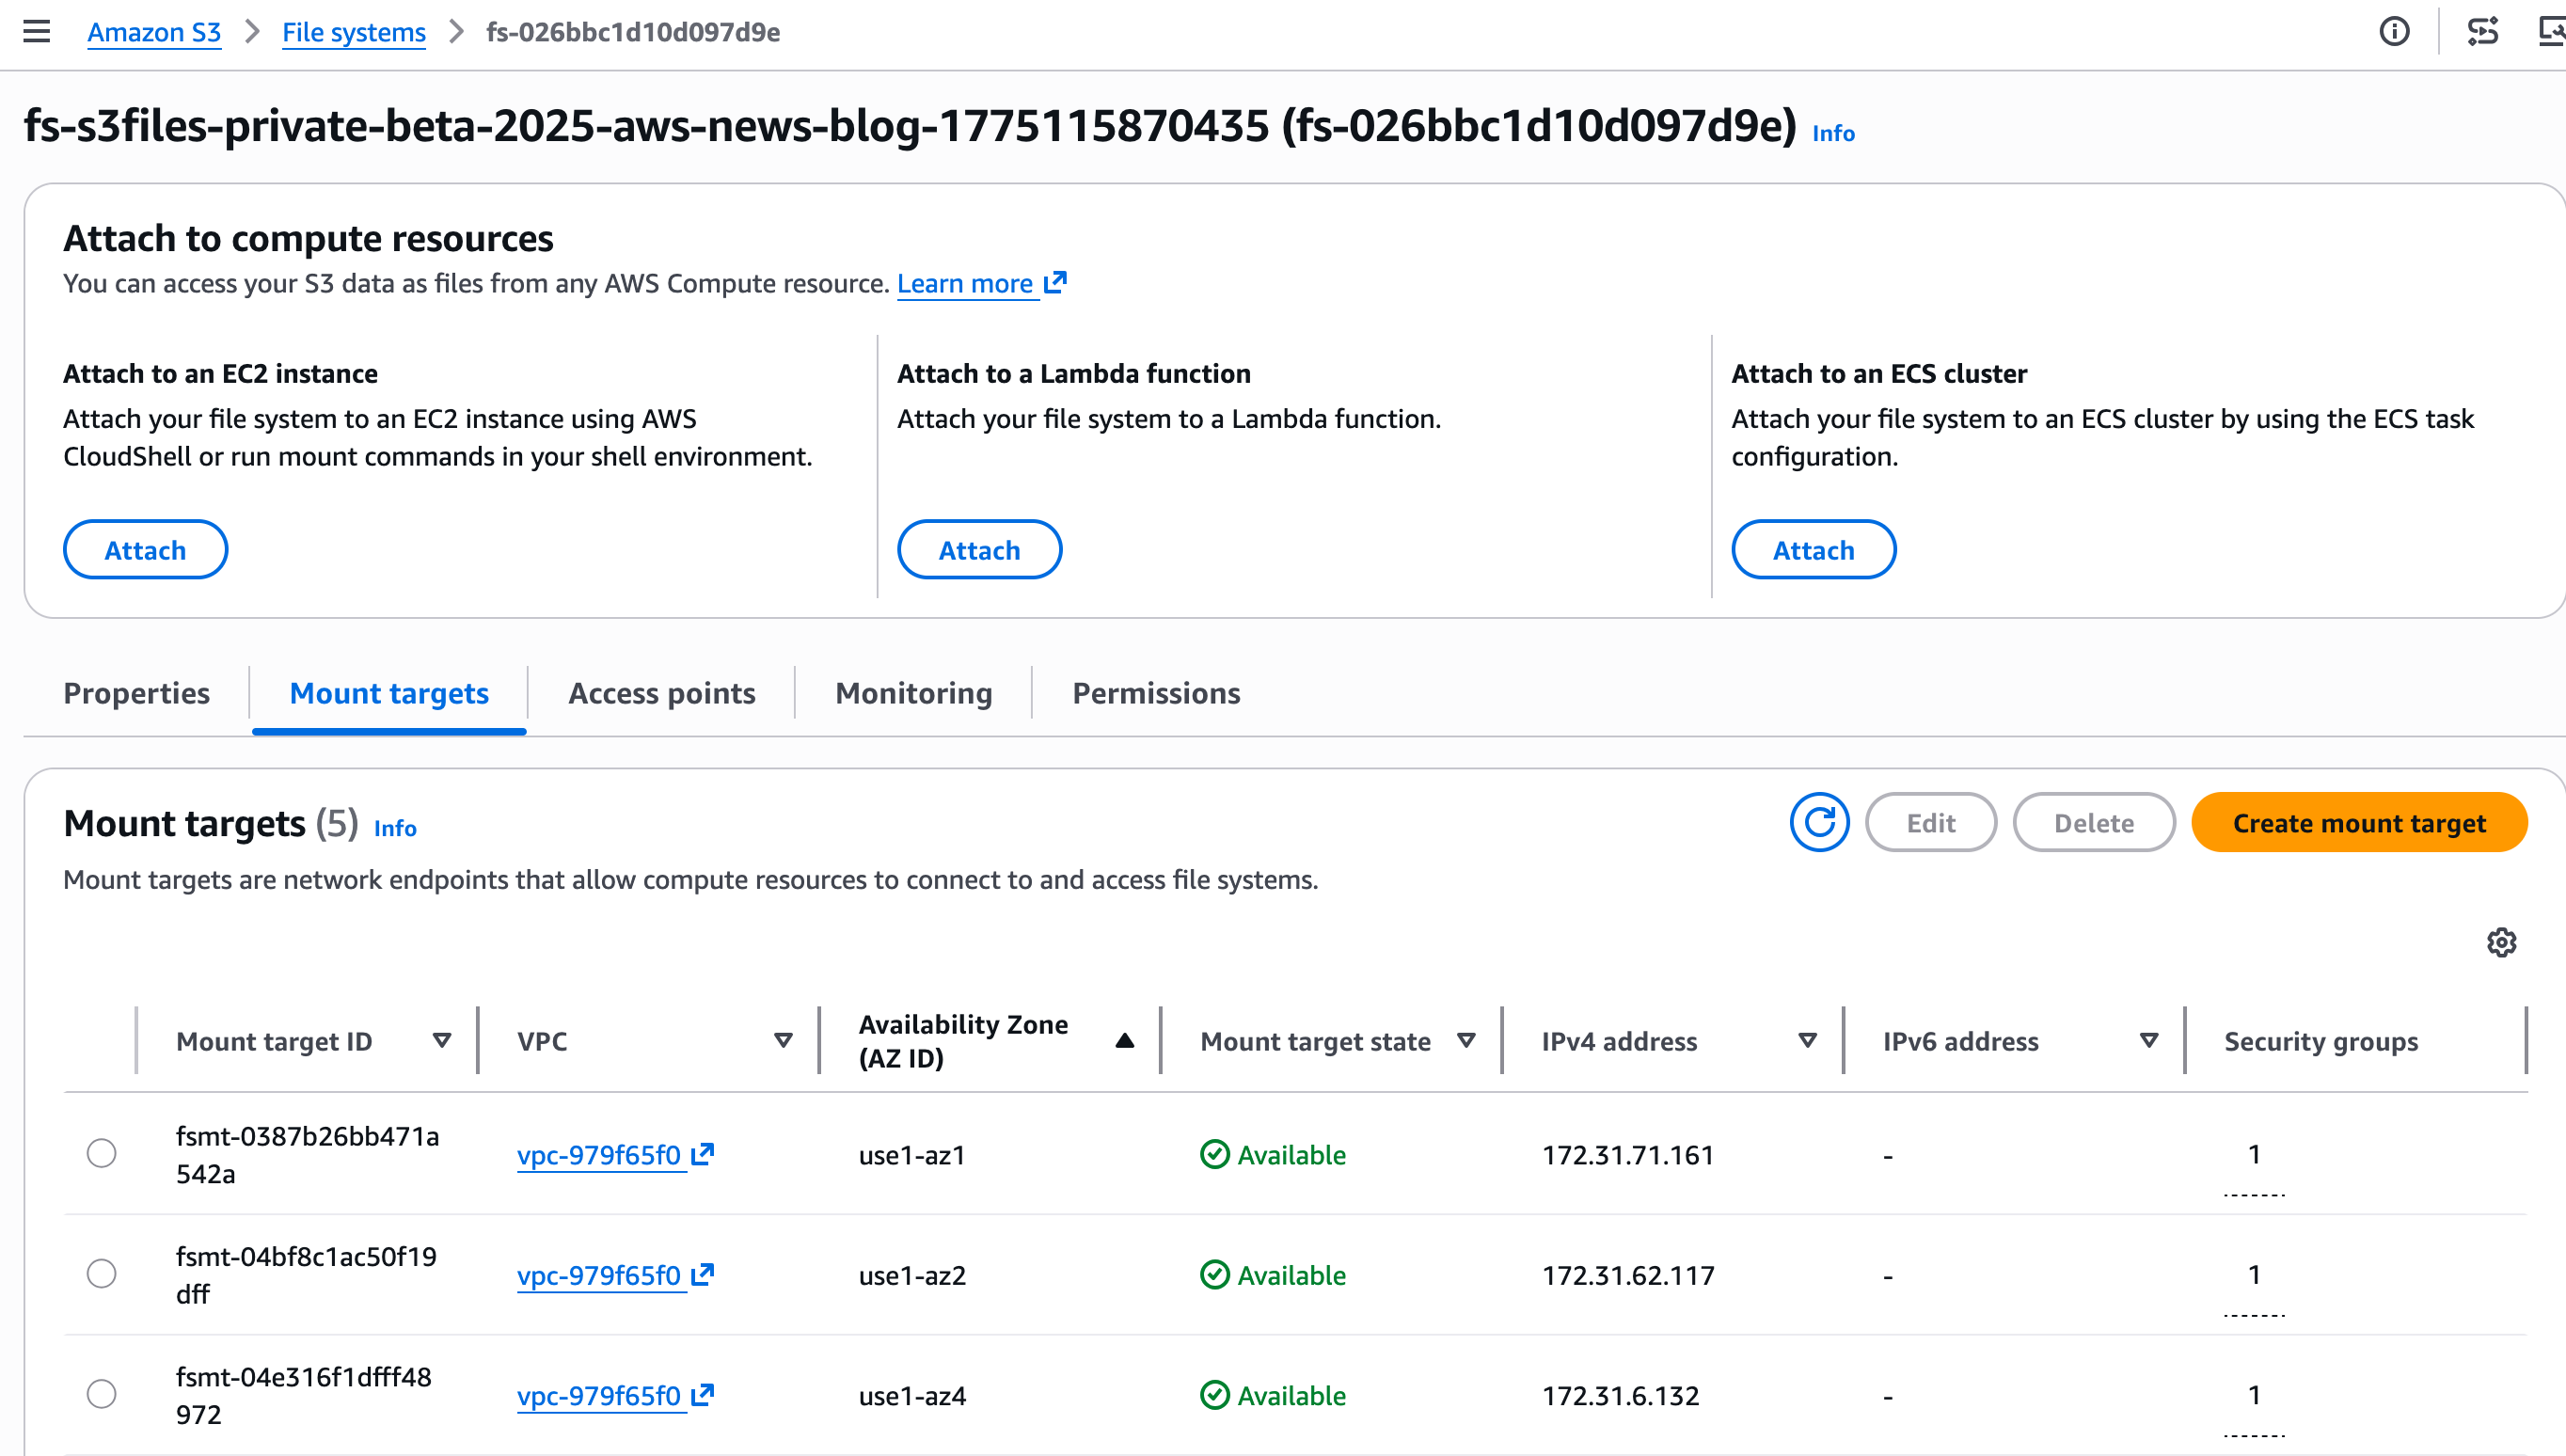
A mount target is a network endpoint that will live in my virtual private cloud (VPC). It allows my EC2 instance to access the S3 file system.

The console creates the mount targets automatically. I take notes of the Mount target IDs on the Mount targets tab.

When using the CLI, two separate commands are necessary to create the file system and its mount targets. First, I create the S3 file system with create-file-system. Then, I create the mount target with create-mount target.

Step 3: Mount the file system on my EC2 instance.

After it’s connected to an EC2 instance, I type:

sudo mkdir /home/ec2-user/s3files sudo mount -t s3files fs-0aa860d05df9afdfe:/ /home/ec2-user/s3files

I can now work with my S3 data directly through the mounted file system in ~/s3files, using standard file operations.

When I make updates to my files in the file system, S3 automatically manages and exports all updates as a new object or a new version on an existing object back in my S3 bucket within minutes.

Changes made to objects on the S3 bucket are visible in the file system within a few seconds but can sometimes take a minute or longer.

# Create a file on the EC2 file system 
echo "Hello S3 Files" > s3files/hello.txt 

# and verify it's here 
ls -al s3files/hello.txt
 -rw-r--r--. 1 ec2-user ec2-user 15 Oct 22 13:03 s3files/hello.txt 

# See? the file is also on S3 
aws s3 ls s3://s3files-aws-news-blog/hello.txt 
2025-10-22 13:04:04 15 hello.txt 

# And the content is identical! 
aws s3 cp s3://s3files-aws-news-blog/hello.txt . && cat hello.txt
Hello S3 Files

Things to know
Let me share some important technical details that I think you’ll find useful.

Another question I frequently hear in customer conversations is about choosing the right file service for your workloads. Yes, I know what you’re thinking: AWS and its seemingly overlapping services, keeping cloud architects entertained during their architecture review meetings. Let me help demystify this one.

S3 Files works best when you need interactive, shared access to data that lives in Amazon S3 through a high performance file system interface. It’s ideal for workloads where multiple compute resources—whether production applications, agentic AI agents using Python libraries and CLI tools, or machine learning (ML) training pipelines—need to read, write, and mutate data collaboratively. You get shared access across compute clusters without data duplication, sub-millisecond latency, and automatic synchronization with your S3 bucket.

For workloads migrating from on-premises NAS environments, Amazon FSx provides the familiar features and compatibility you need. Amazon FSx is also ideal for high-performance computing (HPC) and GPU cluster storage with Amazon FSx for Lustre. It’s particularly valuable when your applications require specific file system capabilities from Amazon FSx for NetApp ONTAP, Amazon FSx for OpenZFS, or Amazon FSx for Windows File Server.

Pricing and availability
S3 Files is available today in all commercial AWS Regions.

You pay for the portion of data stored in your S3 file system, for small file read and all write operations to the file system, and for S3 requests during data synchronization between the file system and the S3 bucket. The Amazon S3 pricing page has all the details.

From discussions with customers, I believe S3 Files helps simplify cloud architectures by eliminating data silos, synchronization complexity, and manual data movement between objects and files. Whether you’re running production tools that already work with file systems, building agentic AI systems that rely on file-based Python libraries and shell scripts, or preparing datasets for ML training, S3 Files lets these interactive, shared, hierarchical workloads access S3 data directly without choosing between the durability of Amazon S3 and cost benefits and a file system’s interactive capabilities. You can now use Amazon S3 as the place for all your organizations’ data, knowing the data is accessible directly from any AWS compute instance, container, and function.

To learn more and get started, visit the S3 Files documentation.

I’d love to hear how you use this new capability. Feel free to share your feedback in the comments below.

— seb
Building AI defenses at scale: Before the threats emerge

Post Syndicated from Amy Herzog original https://aws.amazon.com/blogs/security/building-ai-defenses-at-scale-before-the-threats-emerge/

At AWS, we’ve spent decades developing processes and tools that enable us to defend millions of customers simultaneously, wherever they operate around the world. Every day, our security and threat intelligence teams are doing work with AI and automation that most people never see. Our AI-powered log analysis system has reduced the time SecOps engineers spend analyzing security logs from an average of six hours to just seven minutes, a 50x productivity increase that lets us detect and respond to threats faster than ever. Across AWS, we analyze over 400 trillion network flows per day to detect patterns that signal emerging threats. In 2025 alone, we blocked over 300 million attempts to maliciously encrypt customer files hosted on Amazon S3.

What we learn protecting one customer helps protect all customers. At this scale, every threat we see makes our defenses stronger for everyone, and AI is already central to how we do it.

A new class of AI for cybersecurity

Today, Anthropic announced Project Glasswing, a cybersecurity initiative designed to secure the world’s most critical software and advance the cybersecurity practices the industry will need as AI grows more capable. Organizations that build or maintain critical digital infrastructure are getting early access to Claude Mythos Preview, a new class of AI model, to find and patch vulnerabilities in the systems the world depends on. Given our role in securing some of the world’s most essential infrastructure, AWS is playing an integral part in advancing this work.

Powering the project is Claude Mythos Preview, Anthropic’s most advanced AI model to date and a step-change in reasoning and AI capabilities for cybersecurity. Claude Mythos Preview represents a fundamentally new model class: more intelligent and capable than Anthropic’s previous frontier models, with higher performance on cybersecurity, software coding, and complex reasoning tasks.

As part of Project Glasswing, we’ve already applied Claude Mythos Preview to critical AWS codebases that undergo continuous AI-powered security reviews, and even in those well-tested environments, it’s helped us identify additional opportunities to strengthen our code. In our internal testing, Claude Mythos Preview has proven more productive than previous models at surfacing security findings, requiring less manual guidance from our engineers to deliver actionable results. We’ve also given early access to a select group of AWS customers, who are deploying Claude Mythos Preview in their own security workflows and helping shape how the model evolves. For us, Claude Mythos Preview is a natural extension of the AI tools we already use, and as the technology grows more powerful, so must our defenses.

This is exactly the kind of innovation that drives our work, and we’ve been working closely with Anthropic to help ensure Claude Mythos Preview is ready for enterprise use. AWS is Anthropic’s primary cloud provider for mission-critical workloads, safety research, and foundation model development. More broadly, AWS provides the foundational infrastructure that the world’s leading AI companies rely on to build, train, and deploy their most advanced models. We’re bringing decades of security experience to this partnership, helping to ensure Claude Mythos Preview is ready for even more organizations to build upon and operate securely at scale.

Claude Mythos Preview signals an upcoming wave of models that can find vulnerabilities and build working exploits at a scale and speed we haven’t seen before. Anthropic and AWS are taking a deliberately cautious approach to release. Access begins with a small number of organizations, prioritizing internet-critical companies and open-source maintainers whose software and digital services impact hundreds of millions of users. The goal: find and fix vulnerabilities in the world’s most critical software. Claude Mythos Preview is available in gated research preview through Amazon Bedrock with enterprise-grade security controls, including customer-managed encryption, VPC isolation, and detailed logging, so your team can explore Claude Mythos Preview’s capabilities without exposing production assets to unnecessary risk.

AWS architects services with security at the core

Our work with Project Glasswing is grounded in a philosophy we’ve developed over two decades of securing mission-critical workloads: you can’t wait for threats to materialize before building your defenses. You have to look around corners, adopt new technologies, build protections first, deploy them in your own operations at scale, and refine them based on what you learn.

That’s exactly what we’ve done at AWS with AI and security. Our approach spans the full spectrum: proactive defense through threat hunting and vulnerability research, dynamic response to active campaigns, and third-party certifications that verify our security practices meet the highest industry standards. This operational experience has taught us where AI accelerates security work and where human judgment remains essential. And it’s reinforced that security innovation must be pragmatic: proven in production before we ask you to rely on it.

That’s also why we help define what secure AI looks like. We became the first major cloud provider to achieve ISO 42001 certification for AI services. We’re active participants in OWASP, the Coalition for Secure AI, and the Frontier Model Safety Framework. And we co-founded the Open Cybersecurity Schema Framework (OCSF) to enable better threat intelligence sharing across the ecosystem. The AWS Nitro System provides mathematical isolation for workloads. Our zero-operator access architecture means AWS personnel can’t access your data. These aren’t aspirational goals. They’re how we operate today, at scale, every day.

Amazon Bedrock is where these principles come to life for AI. It provides policy-enforced access controls, built-in evaluation tools to measure how effectively models identify and validate vulnerabilities, and the ability to run workloads inside your own virtual private cloud. AWS is also the first cloud provider to achieve FedRAMP High and Department of Defense Security Requirements Guide Impact Level 4 and 5 authorizations for generally available Claude foundation models, reinforcing that Amazon Bedrock is where the most security-sensitive organizations already trust Anthropic’s technology.

How to get started today

The same principles that guide our work at AWS scale apply regardless of which AI tools you’re using: comprehensive observability, defense in depth, automation where it adds value, and human judgment where it’s essential. Here’s how to put them into practice.

Prepare for the next generation of AI security. Claude Mythos Preview signals an upcoming wave of AI models that will transform cybersecurity. Start strengthening your security posture now so your organization is ready as these capabilities become more broadly available. Claude Mythos Preview is available in gated preview through Amazon Bedrock, and access is limited to an initial allow-list of organizations. If your organization has been allow-listed, your AWS account team will reach out directly.

Run on-demand penetration testing with AWS Security Agent. Now generally available, AWS Security Agent delivers autonomous penetration testing that operates 24/7 at a fraction of the cost of manual penetration tests. It transforms penetration testing from a periodic bottleneck into an on-demand capability that scales with your development velocity across AWS, Azure, GCP, other cloud providers, and on-premises. AWS Security Agent represents a new class of frontier agents: autonomous systems that work independently to achieve goals, scale to tackle concurrent tasks, and run persistently without constant human oversight. It deploys specialized AI agents to discover, validate, and report security vulnerabilities through sophisticated multi-step attack scenarios. Unlike traditional scanners that generate findings without validation, AWS Security Agent identifies potential vulnerabilities, then attempts to exploit them with targeted payloads and attack chains to confirm they are legitimate security risks. Each finding includes CVSS risk scores, application-specific severity ratings, detailed reproduction steps, and remediation suggestions. The result: penetration testing that once took weeks now completes in hours, and security coverage that scales across your entire application portfolio, not just your most critical systems. New customers can explore AWS Security Agent with a 2-month free trial.

Build AI applications you can trust with Amazon Bedrock. For teams building with generative AI, the challenge isn’t just making AI work, it’s making AI work safely. Amazon Bedrock provides the security and safety controls you need to deploy AI responsibly. Its Automated Reasoning capability is the first and only AI safeguard to use formal logic to help prevent factual errors from hallucinations, providing verifiable explanations with 99% accuracy, a capability we’ve refined over more than a decade of applying formal methods across AWS storage, identity, and networking. Amazon Bedrock also provides customizable guardrails that block harmful content and enforce your content policies, along with comprehensive observability to track AI behavior and detect anomalies across your workloads.

The threat landscape isn’t waiting

The threat landscape isn’t waiting for us to catch up. Nation-state actors, ransomware operators, and supply chain attackers are already using AI to scale their operations. Our job is to stay ahead by building defenses first, deploying them at scale, and sharing what we learn so the entire community benefits.

That’s what we do every day at AWS. We prove technology works in our own operations before we ask customers to rely on it. We set standards rather than follow them. And we look around corners to address tomorrow’s challenges today.

As AI capabilities continue to evolve, this approach won’t change. We’ll keep building defenses first, refining them at scale, and working with partners like Anthropic to ensure the next generation of AI security tools meets the real-world needs of enterprises defending at this scale.

Learn More

If you have feedback about this post, submit comments in the Comments section below.

Amy Herzog

Amy Herzog is Vice President and Chief Information Security Officer (CISO) at Amazon Web Services (AWS) where she leads a global organization of cloud security professionals in a company in which security is the top priority. Prior to joining AWS, Amy served as CISO for Amazon’s Devices and Services, Media and Entertainment, and Advertising businesses, overseeing the security of consumer technology offerings such as Alexa+ and Ring, and playing a key role in the secure development of Project Kuiper, Amazon’s initiative to provide fast, reliable broadband to customers and communities around the world through low earth orbit satellites.

Amazon Bedrock Guardrails supports cross-account safeguards with centralized control and management

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-bedrock-guardrails-supports-cross-account-safeguards-with-centralized-control-and-management/

Today, we’re announcing the general availability of cross-account safeguards in Amazon Bedrock Guardrails, a new capability that enables centralized enforcement and management of safety controls across multiple AWS accounts within an organization.

With this new capability, you can specify a guardrail in a new Amazon Bedrock policy within the management account of your organization that automatically enforces configured safeguards across all member entities for every model invocation with Amazon Bedrock. This organization-wide implementation supports uniform protection across all accounts and generative AI applications with centralized control and management. This capability also offers flexibility to apply account-level and application-specific controls depending on use case requirements in addition to organizational safeguards.

  • Organization-level enforcements apply a single guardrail from your organization’s management account to all entities within the organization through policy settings. This guardrail automatically enforces filters across all member entities, including organizational units (OUs) and individual accounts, for all Amazon Bedrock model invocations.
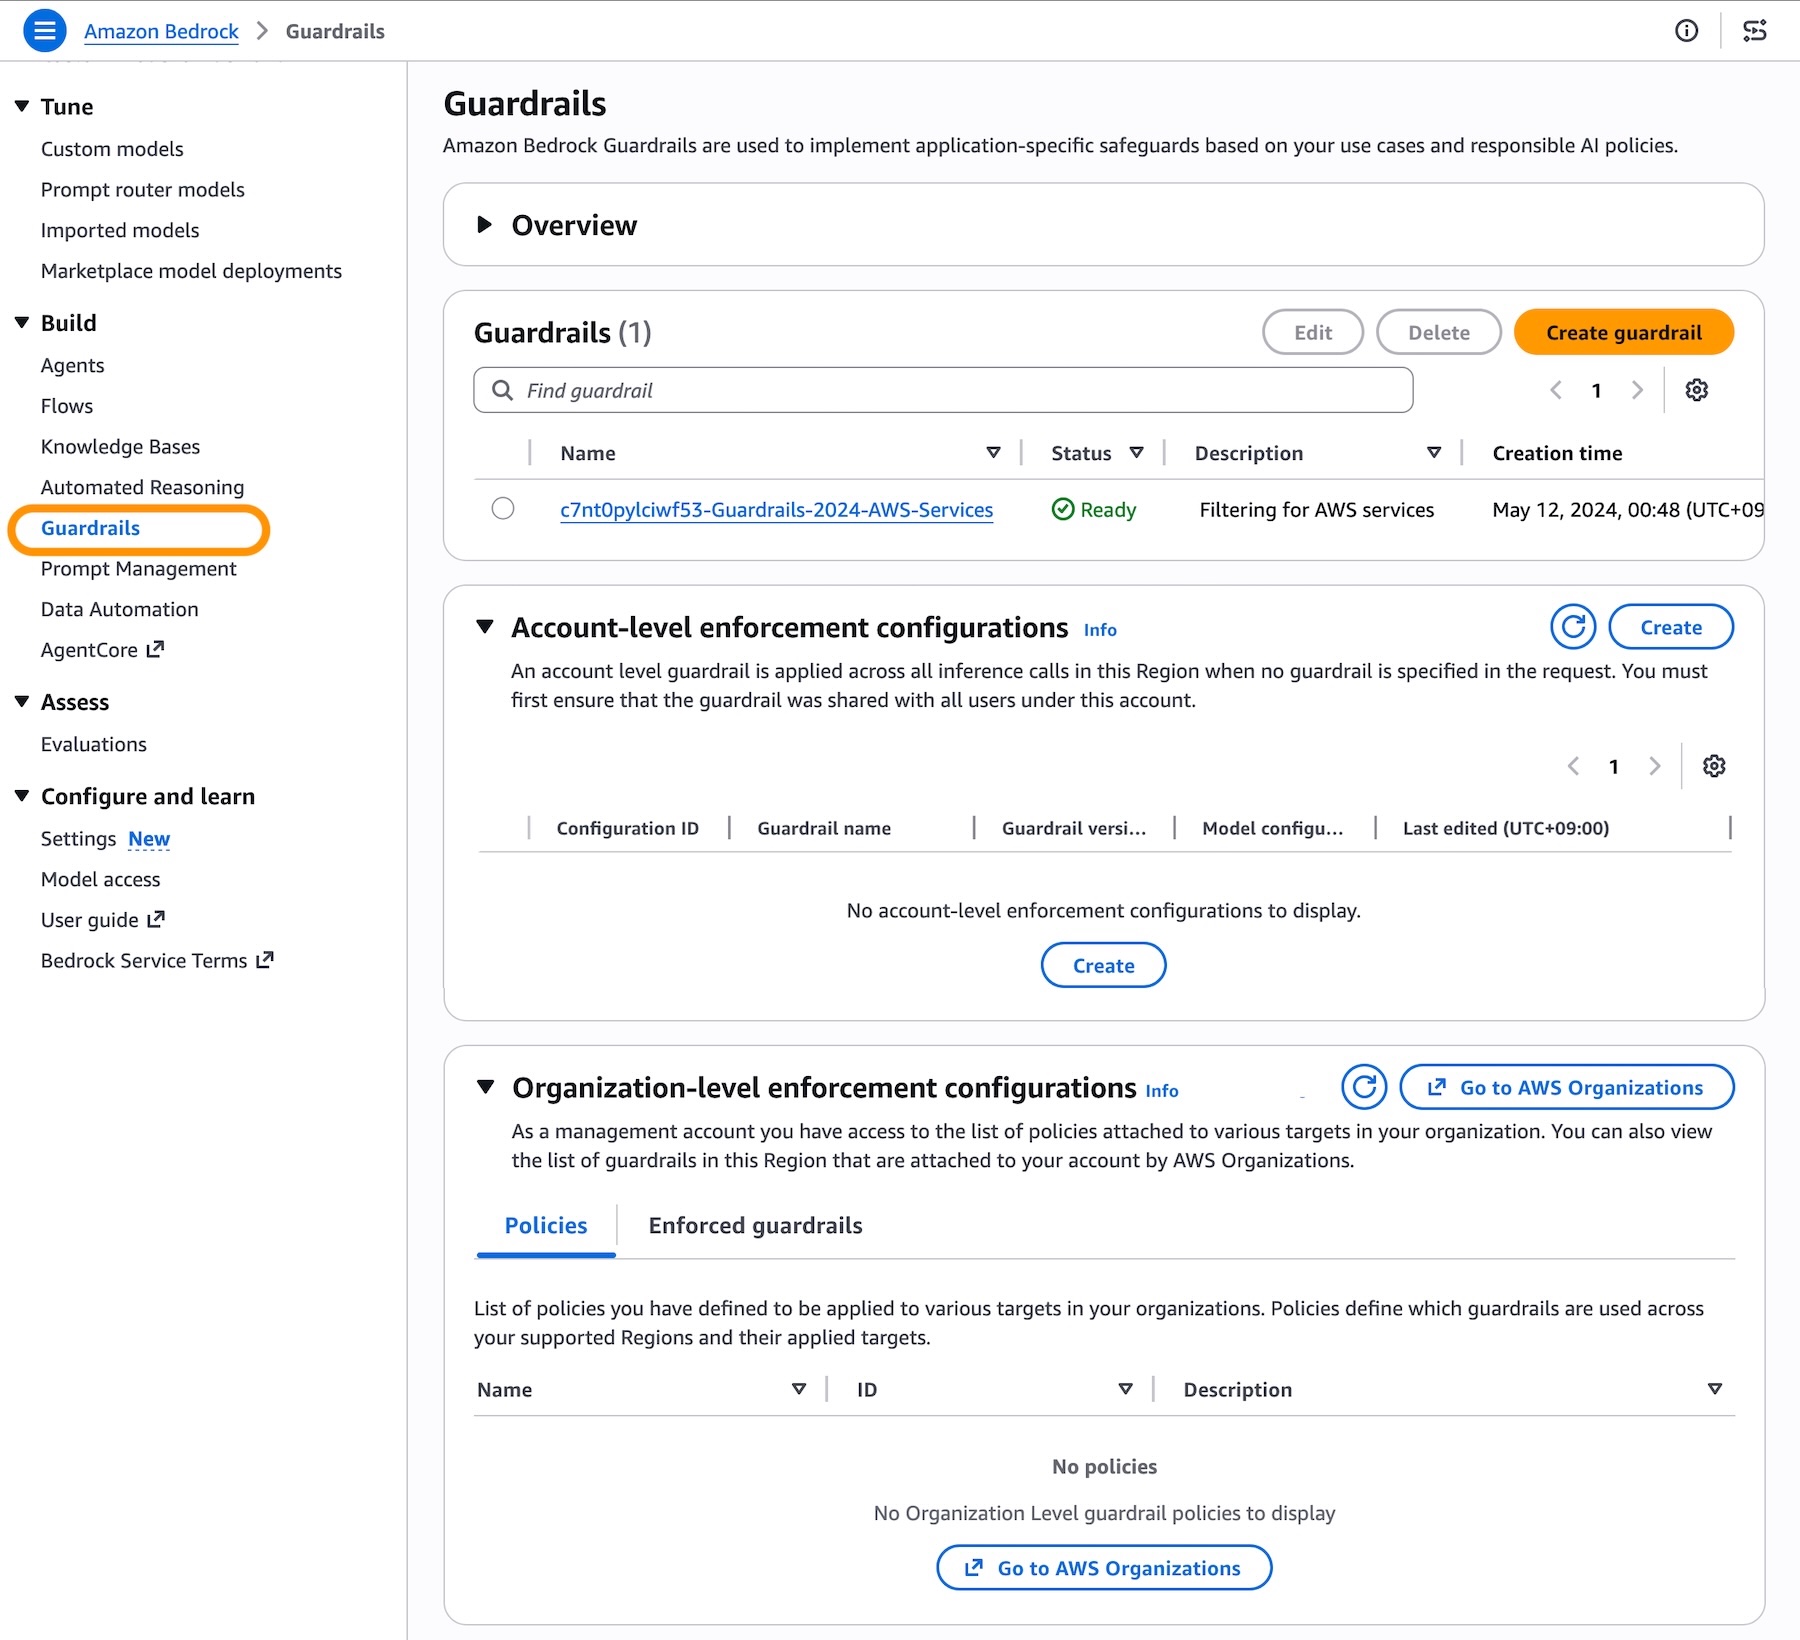
  • Account-level enforcement enables automatic enforcement of configured safeguards across all Amazon Bedrock model invocations in your AWS account. The configured safeguards in the account-level guardrail apply to all inference API calls.

You can now establish and centrally manage dependable, comprehensive protection through a single, unified approach. This supports consistent adherence to corporate responsible AI requirements while significantly reducing the administrative burden of monitoring individual accounts and applications. Your security team no longer needs to oversee and verify configurations or compliance for each account independently.

Getting started with centralized enforcement in Amazon Bedrock Guardrails
You can get started with account-level and organization-level enforcement configuration in the Amazon Bedrock Guardrails console. Before the enforcement configuration, you need to create a guardrail with a particular version to support the guardrail configuration remains immutable and cannot be modified by member accounts and complete prerequisites for using the new capability such as resource-based policies for guardrails.

To enable account-level enforcement, choose Create in the section of Account-level enforcement configurations.

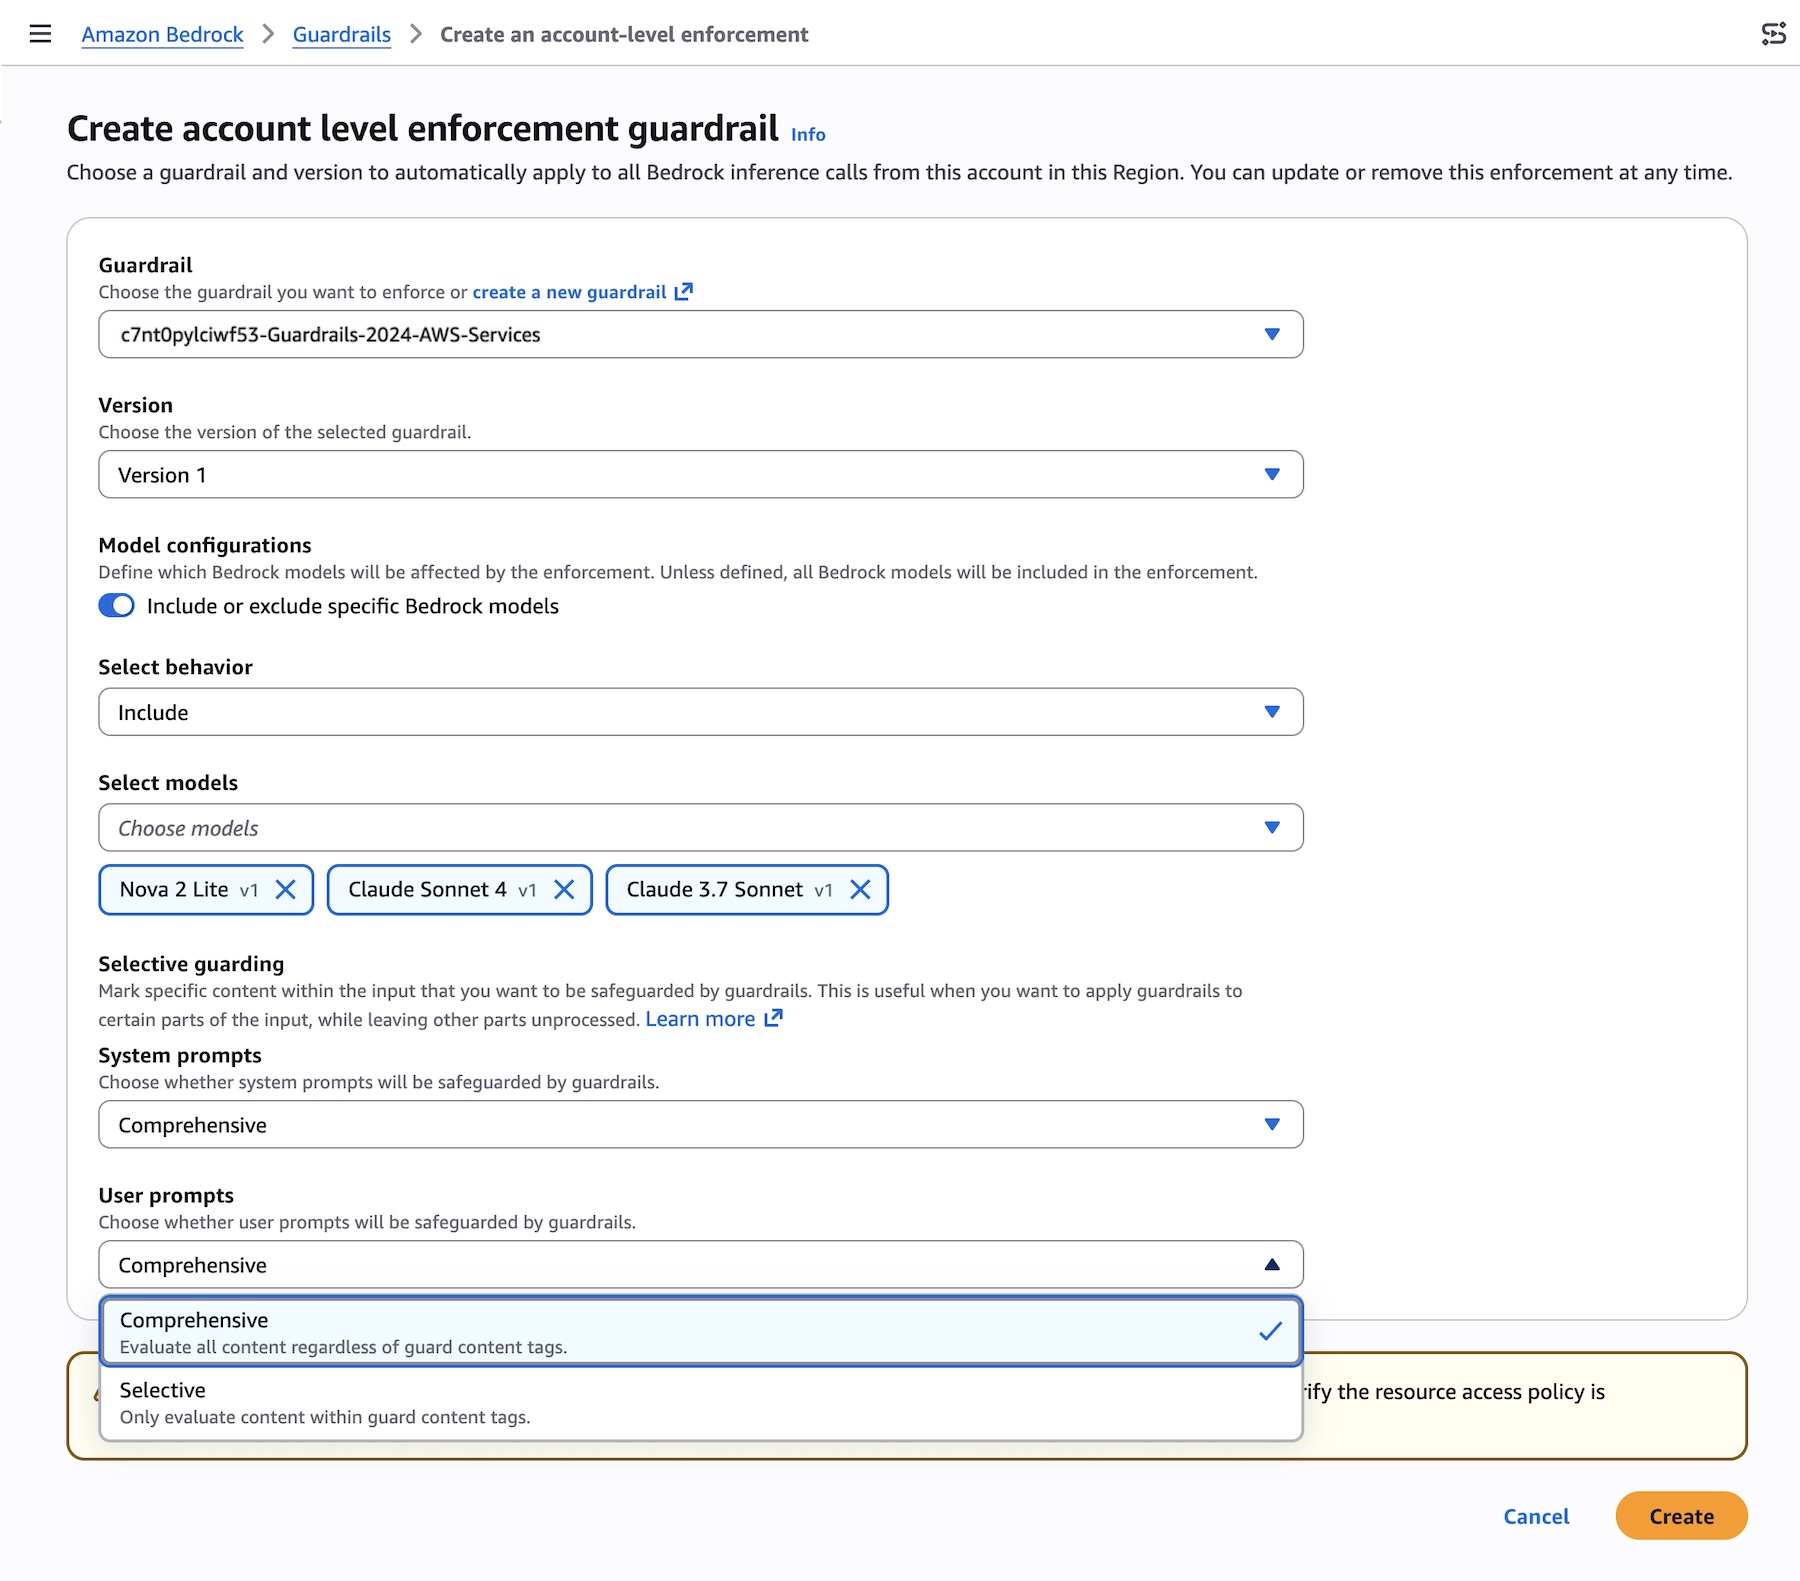
You can choose the guardrail and version to automatically apply to all Bedrock inference calls from this account in this Region. With general availability, we introduce the new feature defining which models will be affected by the enforcement with either Include or Exclude behavior.

You can also configure selective content guarding controls for system prompts and user prompts with either Comprehensive or Selective.

  • Use Comprehensive when you want to enforce guardrails on everything, regardless of what the caller tags. This is the safer default when you don’t want to rely on callers to correctly identify sensitive content.
  • Use Selective when you trust callers to tag the right content and want to reduce unnecessary guardrail processing. This is useful when callers handle a mix of pre-validated and user-generated content, and only need guardrails applied to specific portions.

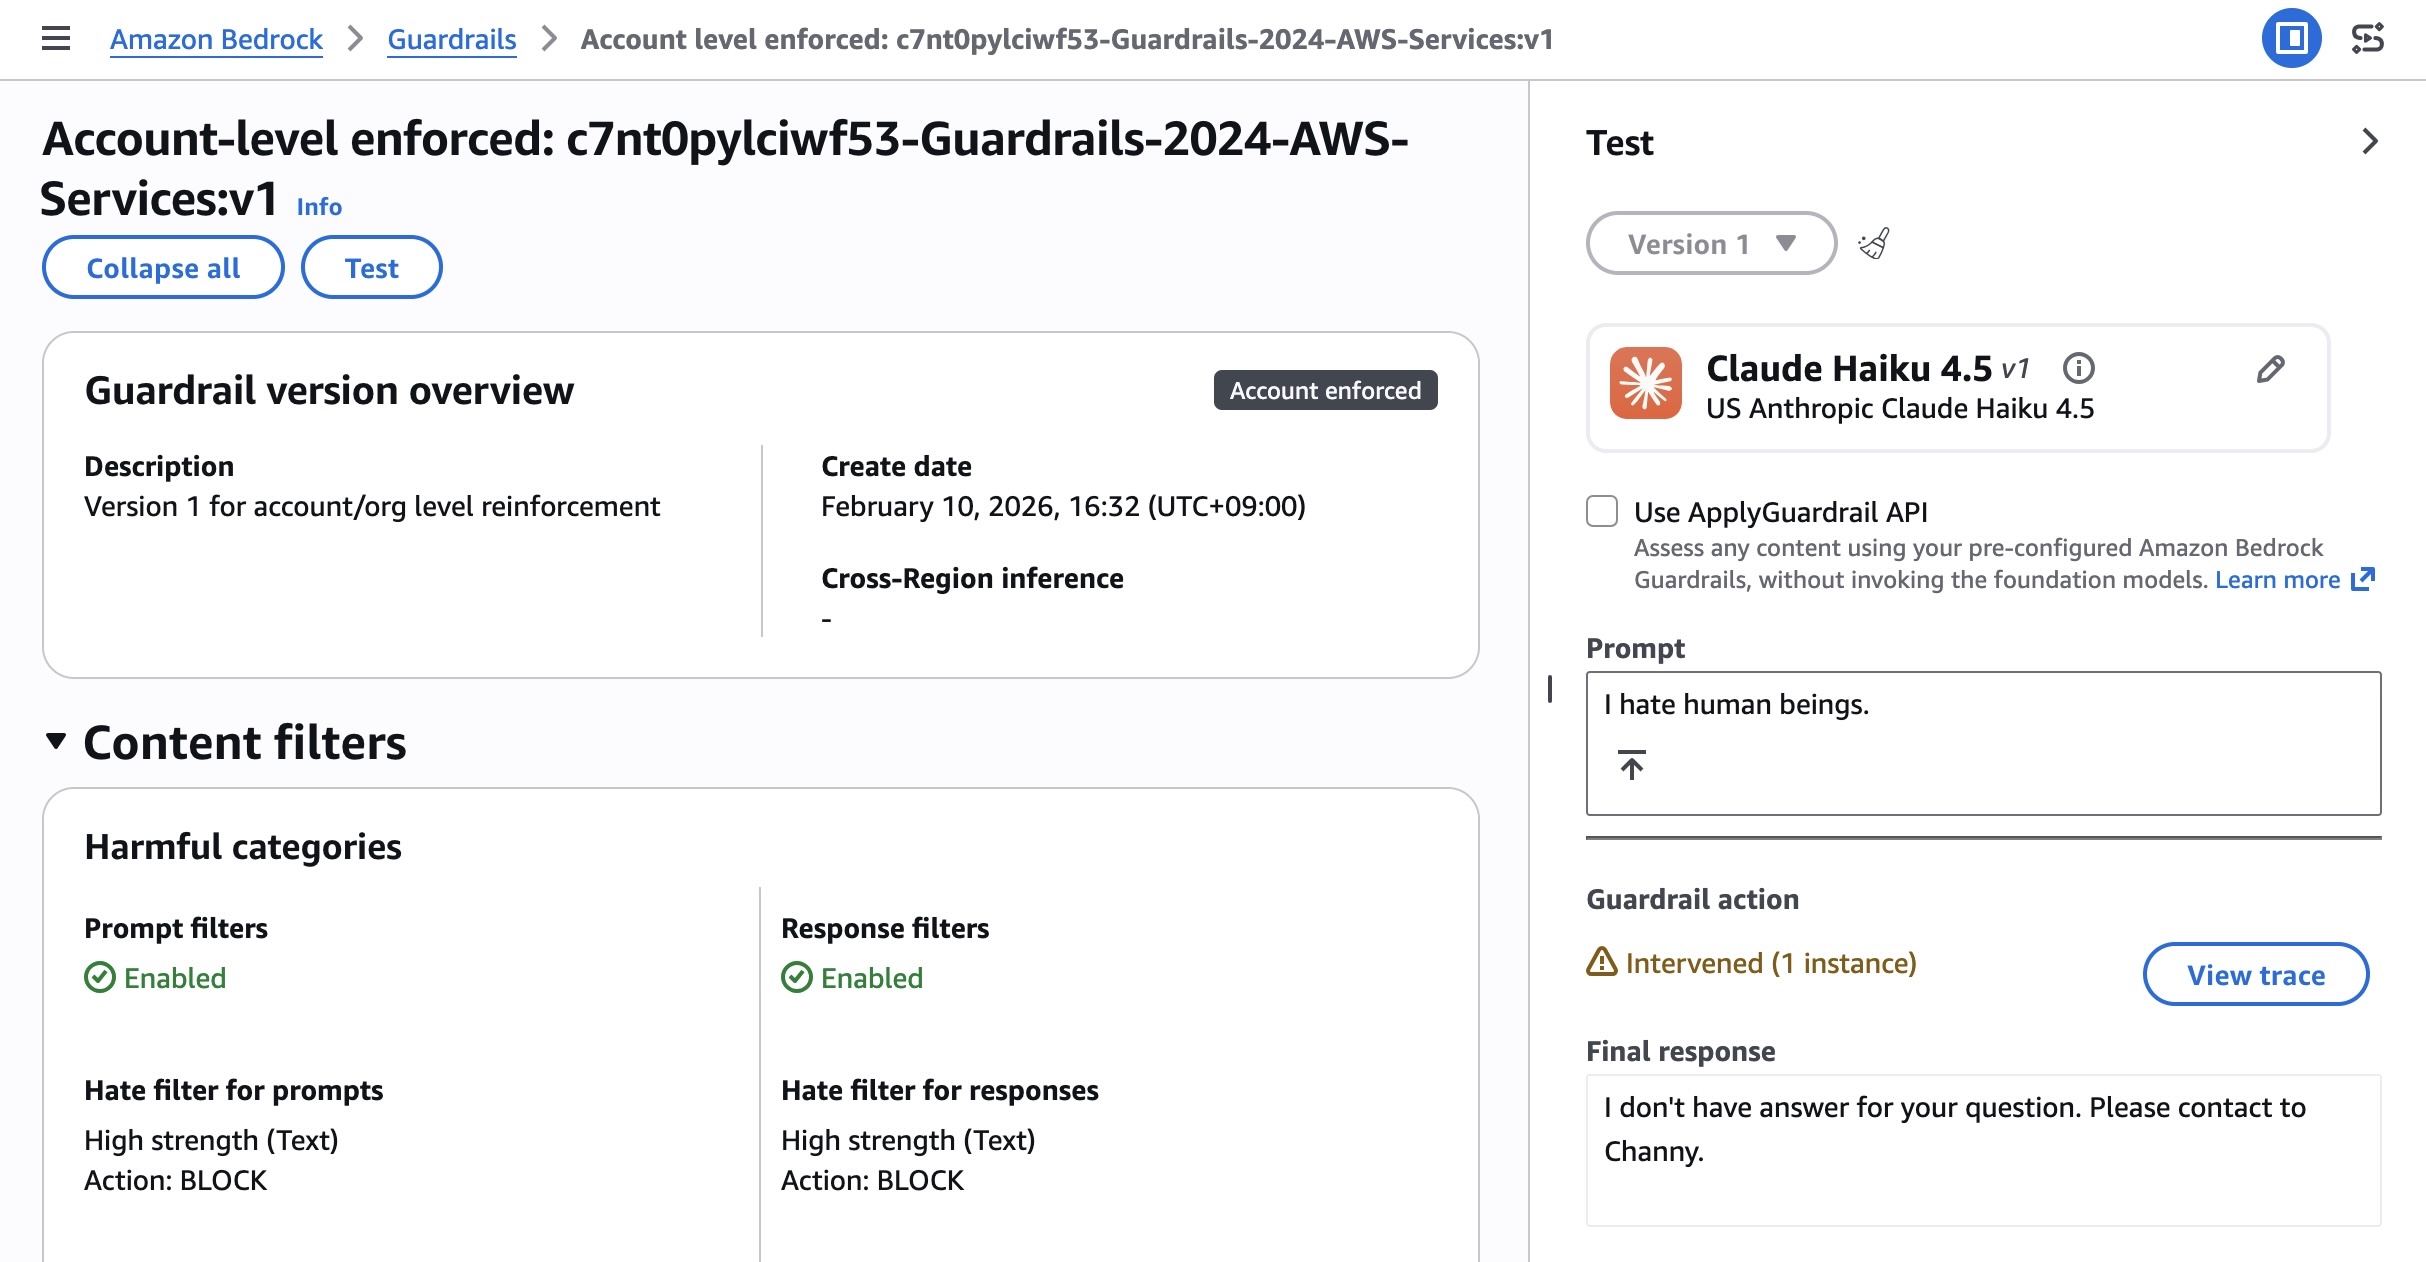
After creating the enforcement, you can test and verify enforcement using a role in your account. The account-enforced guardrail should automatically apply to both prompts and outputs.

Check the response for guardrail assessment information. The guardrail response will include enforced guardrail information. You can also test by making a Bedrock inference call using InvokeModel, InvokeModelWithResponseStream, Converse, or ConverseStream APIs.

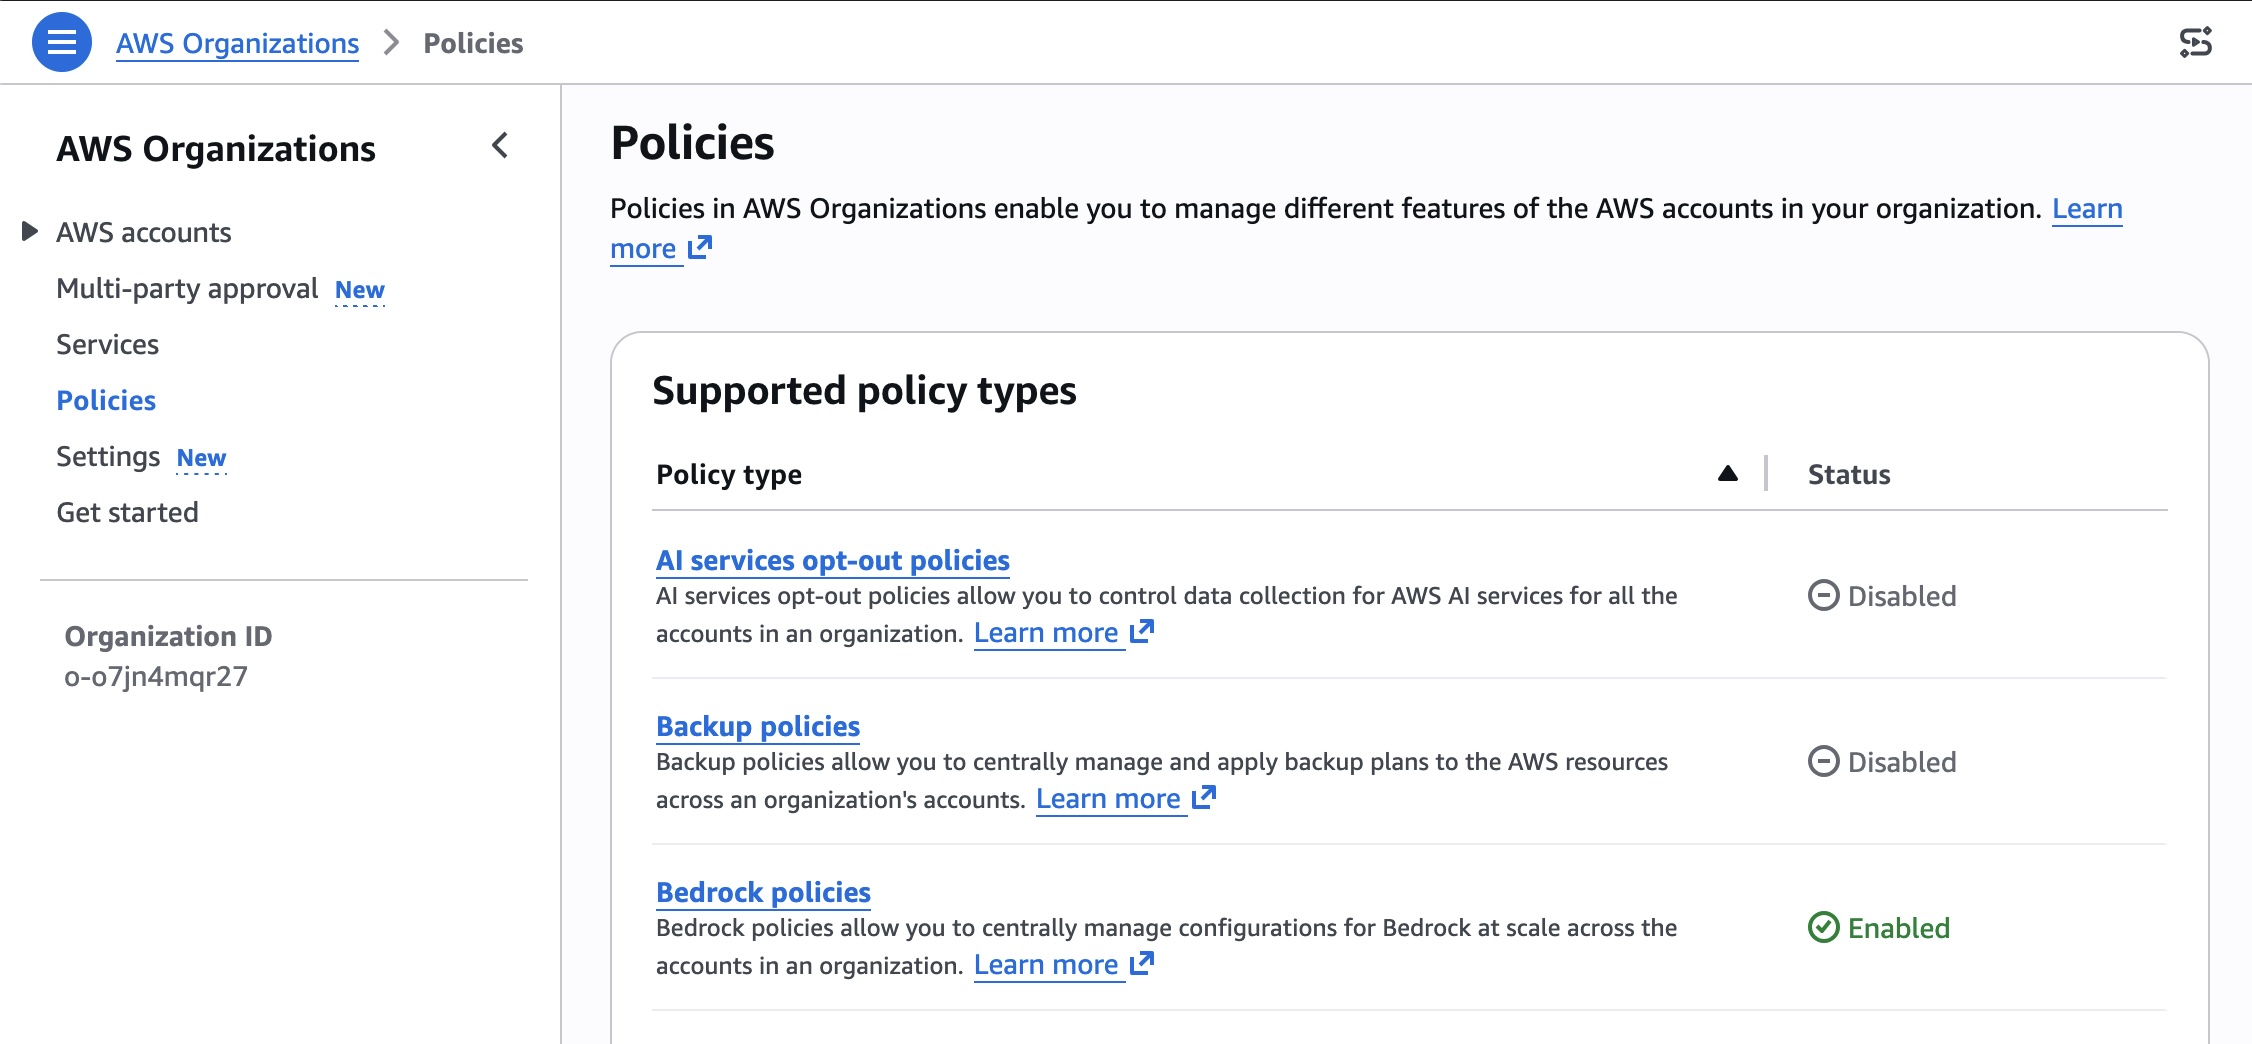
To enable organization-level enforcement, go to AWS Organizations console and choose Policies menu. You can enable the Bedrock policies in the console.

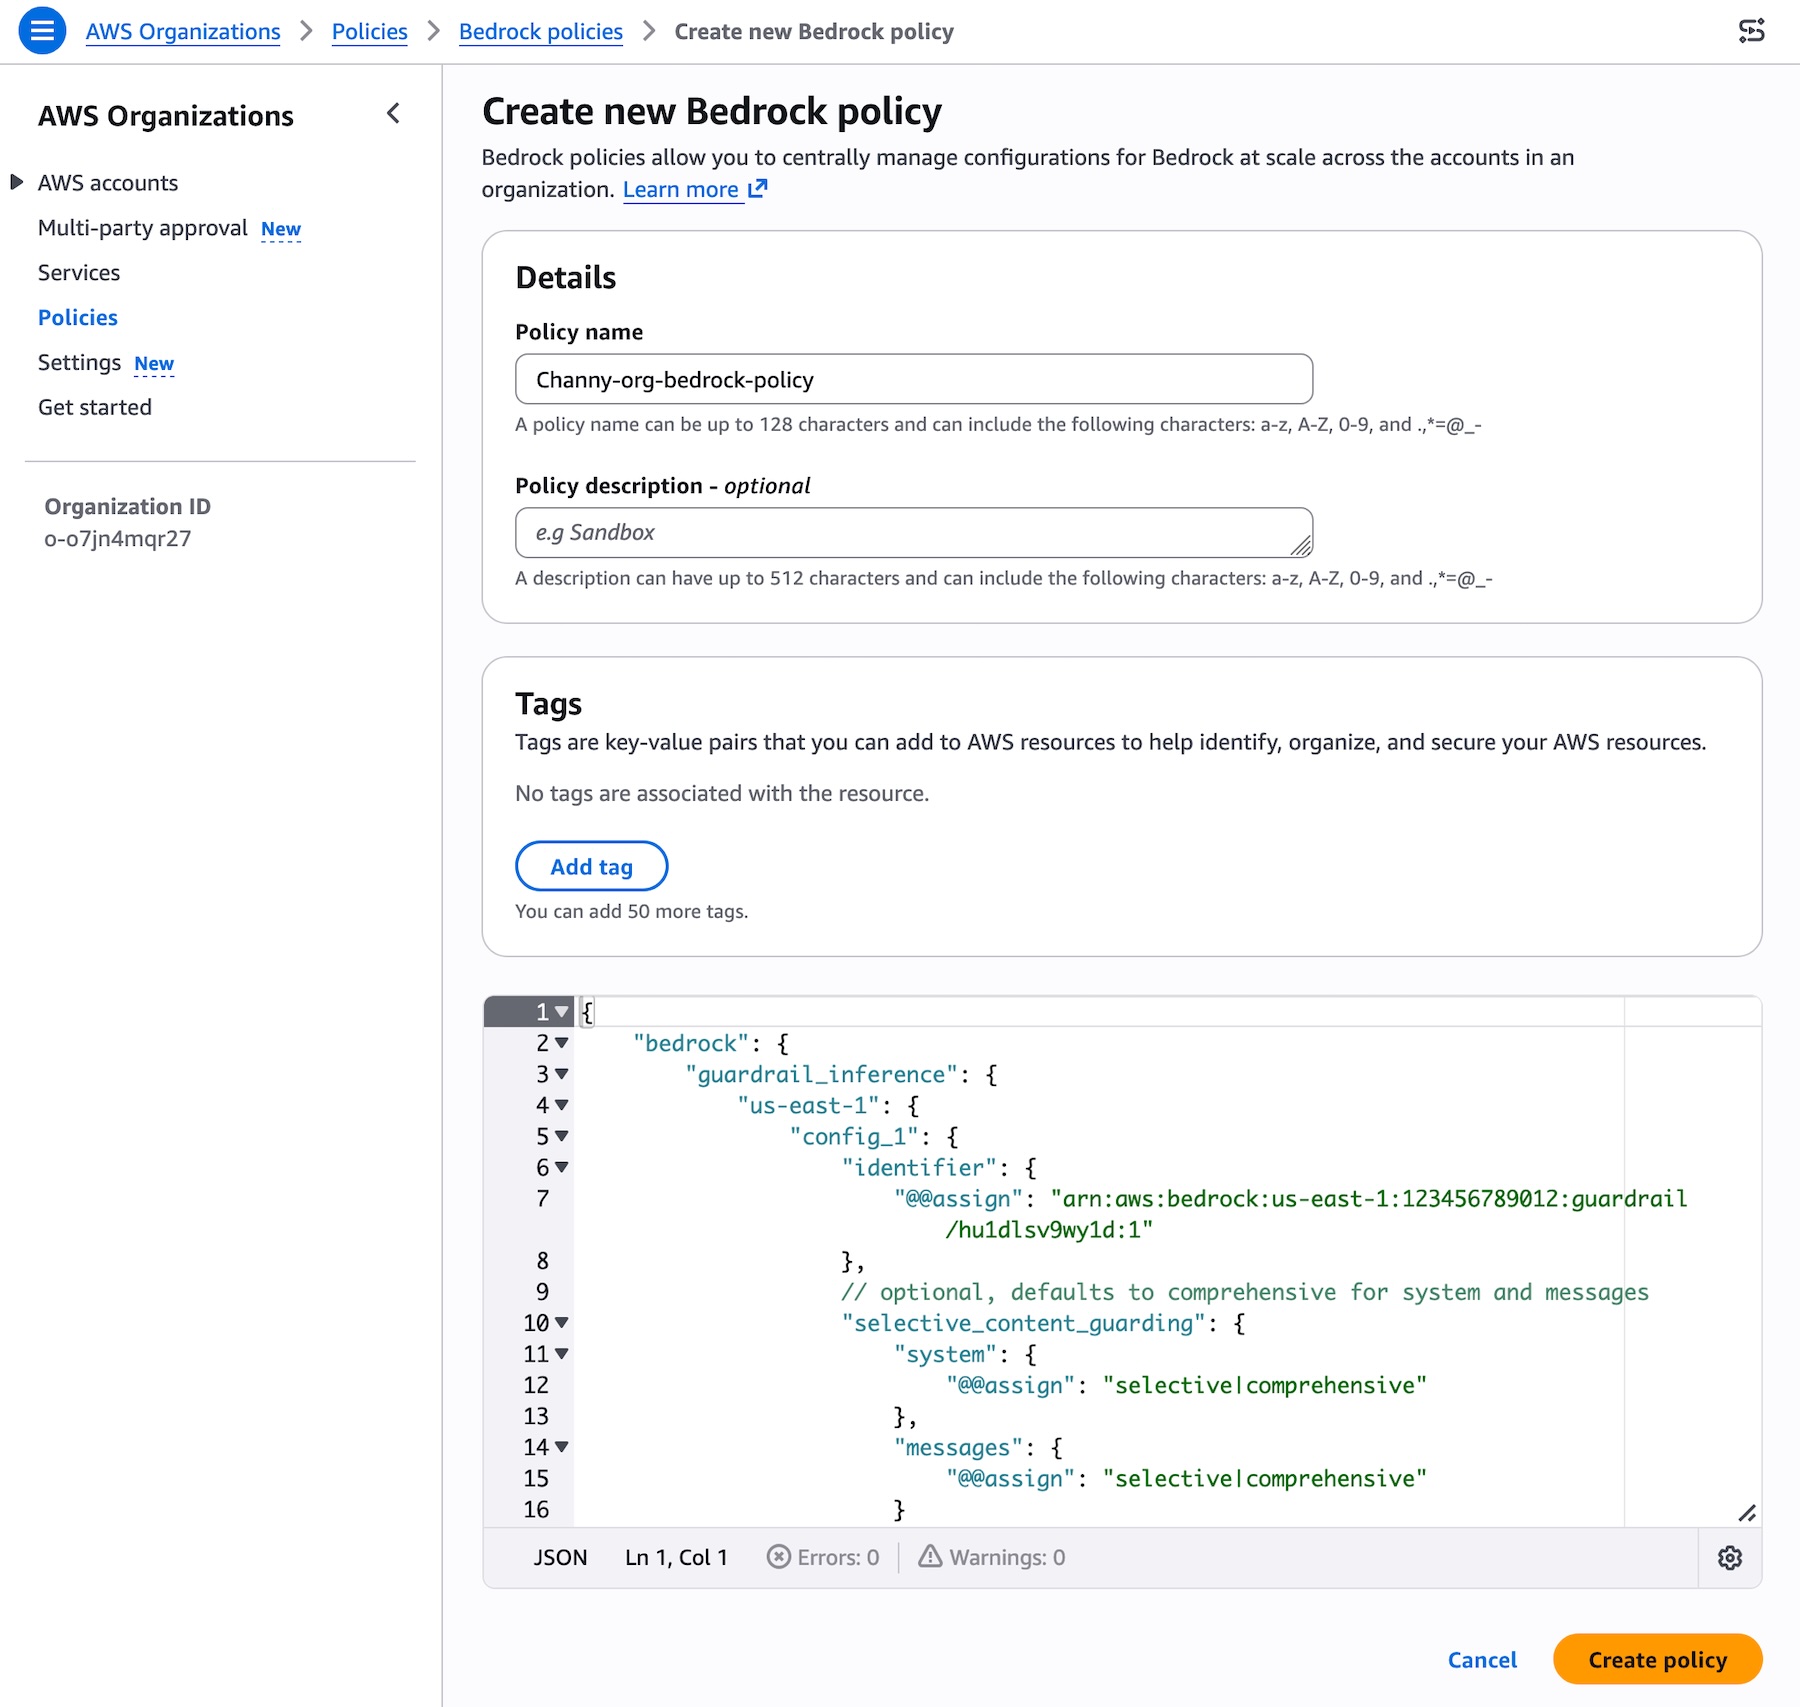
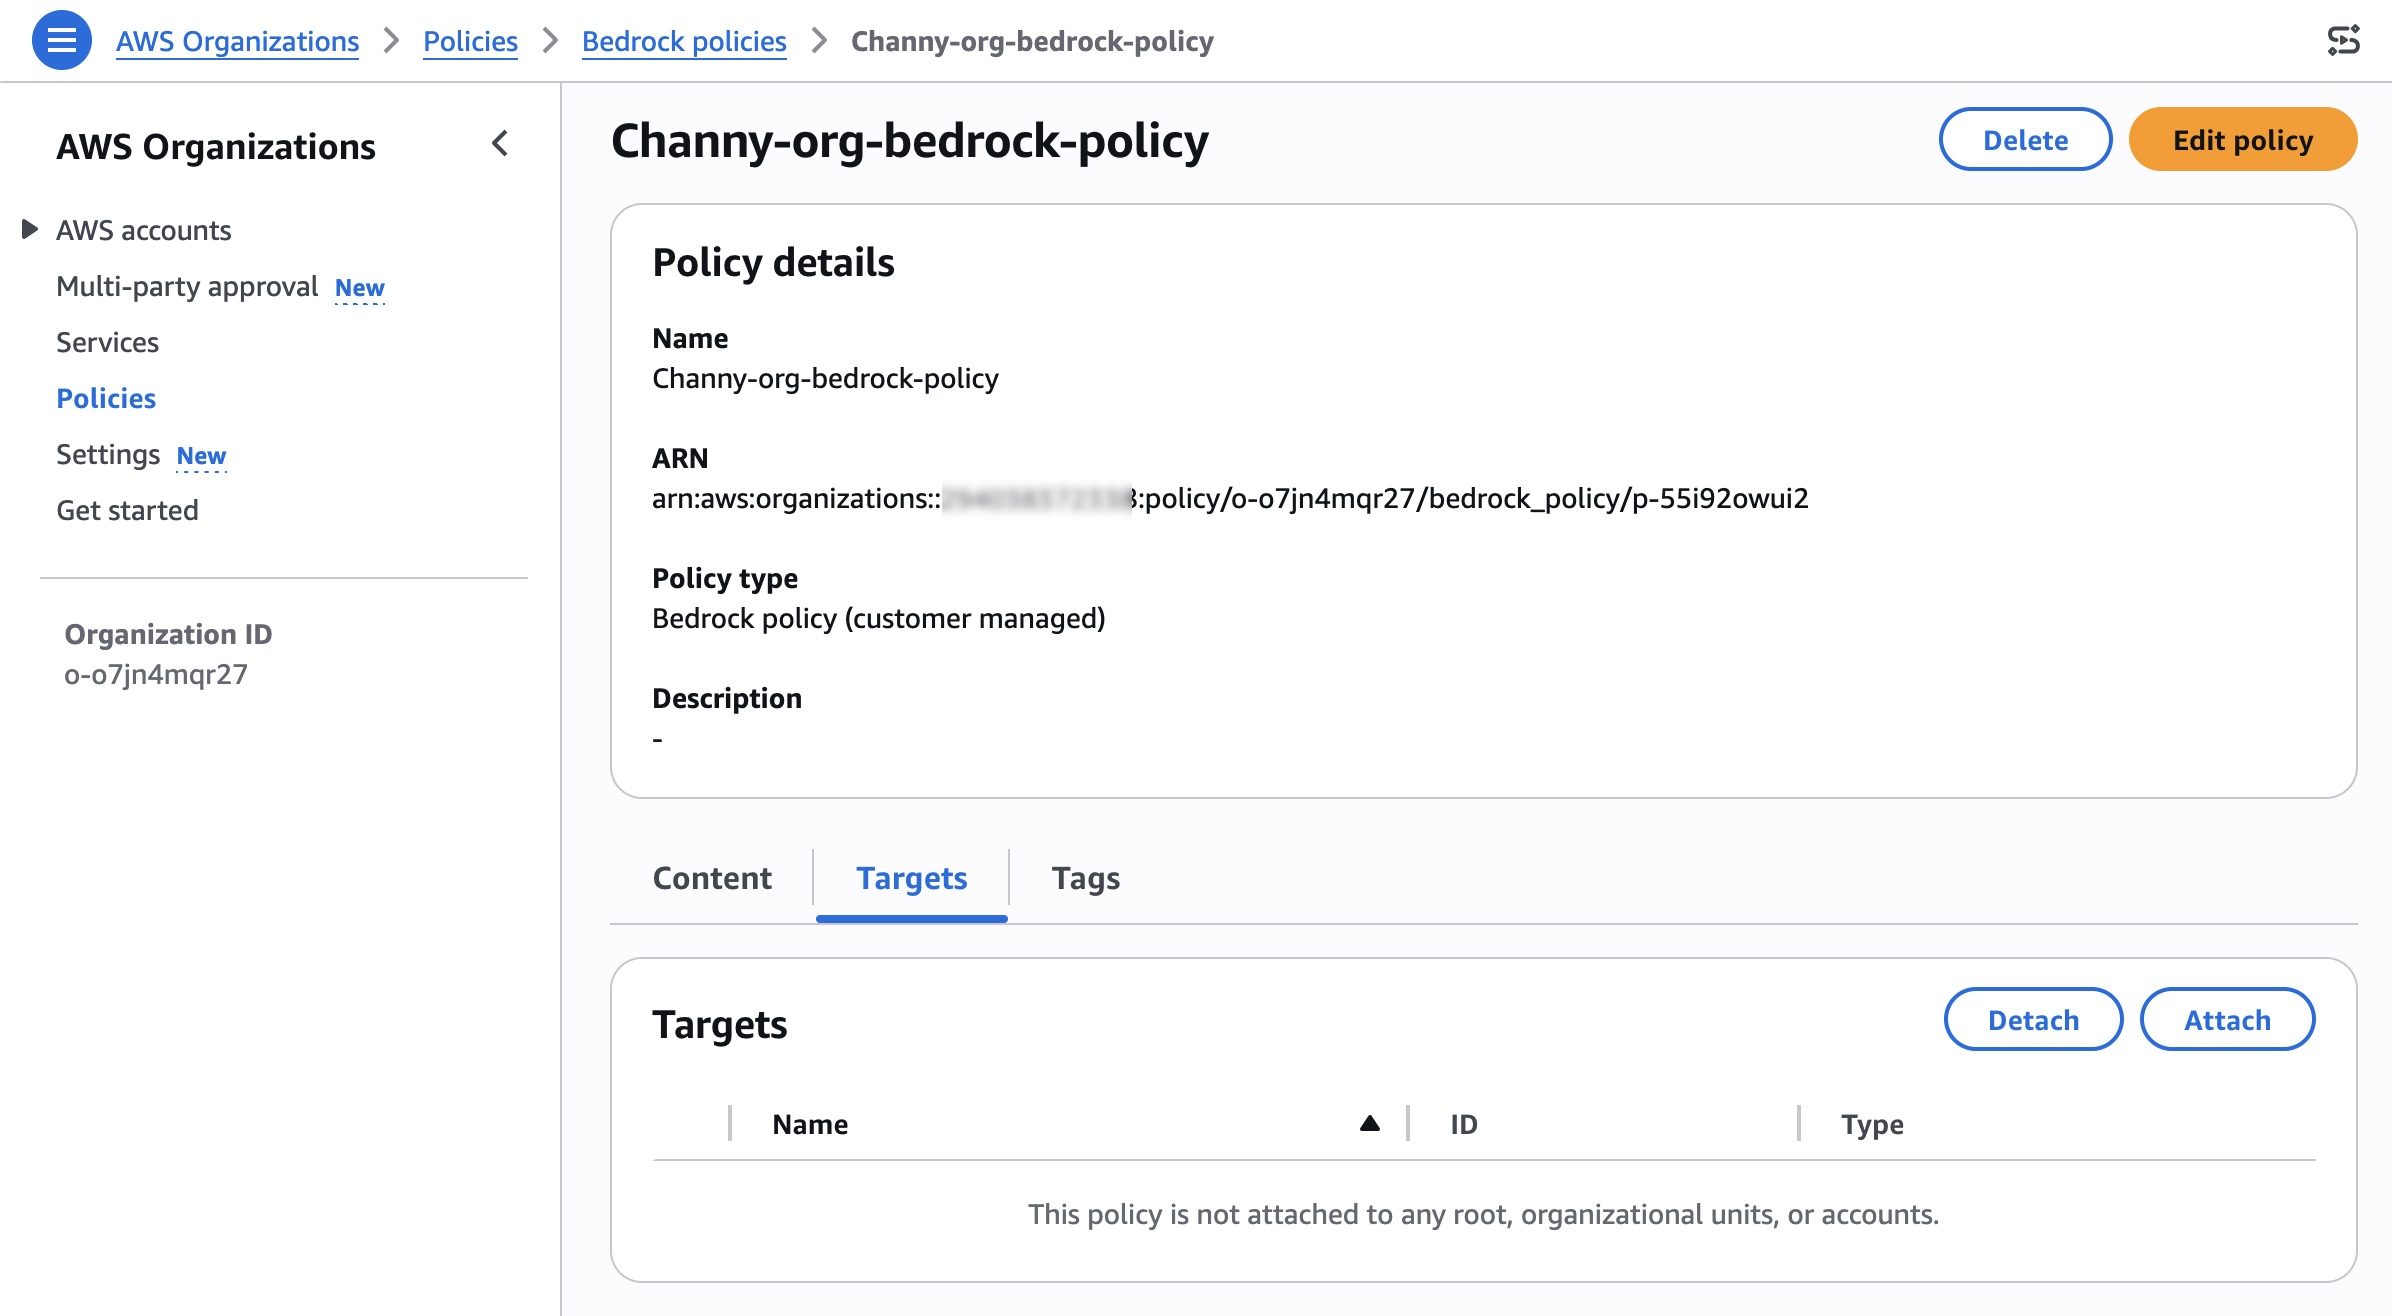
You can create a Bedrock policy that specifies your guardrail and attach it to your target accounts or OUs. Choose Bedrock policies enabled and Create policy. Specify your guardrail ARN and version and configure the input tags setting for in the AWS Organizations. To learn more, visit Amazon Bedrock policies in AWS Organizations and Amazon Bedrock policy syntax and examples.

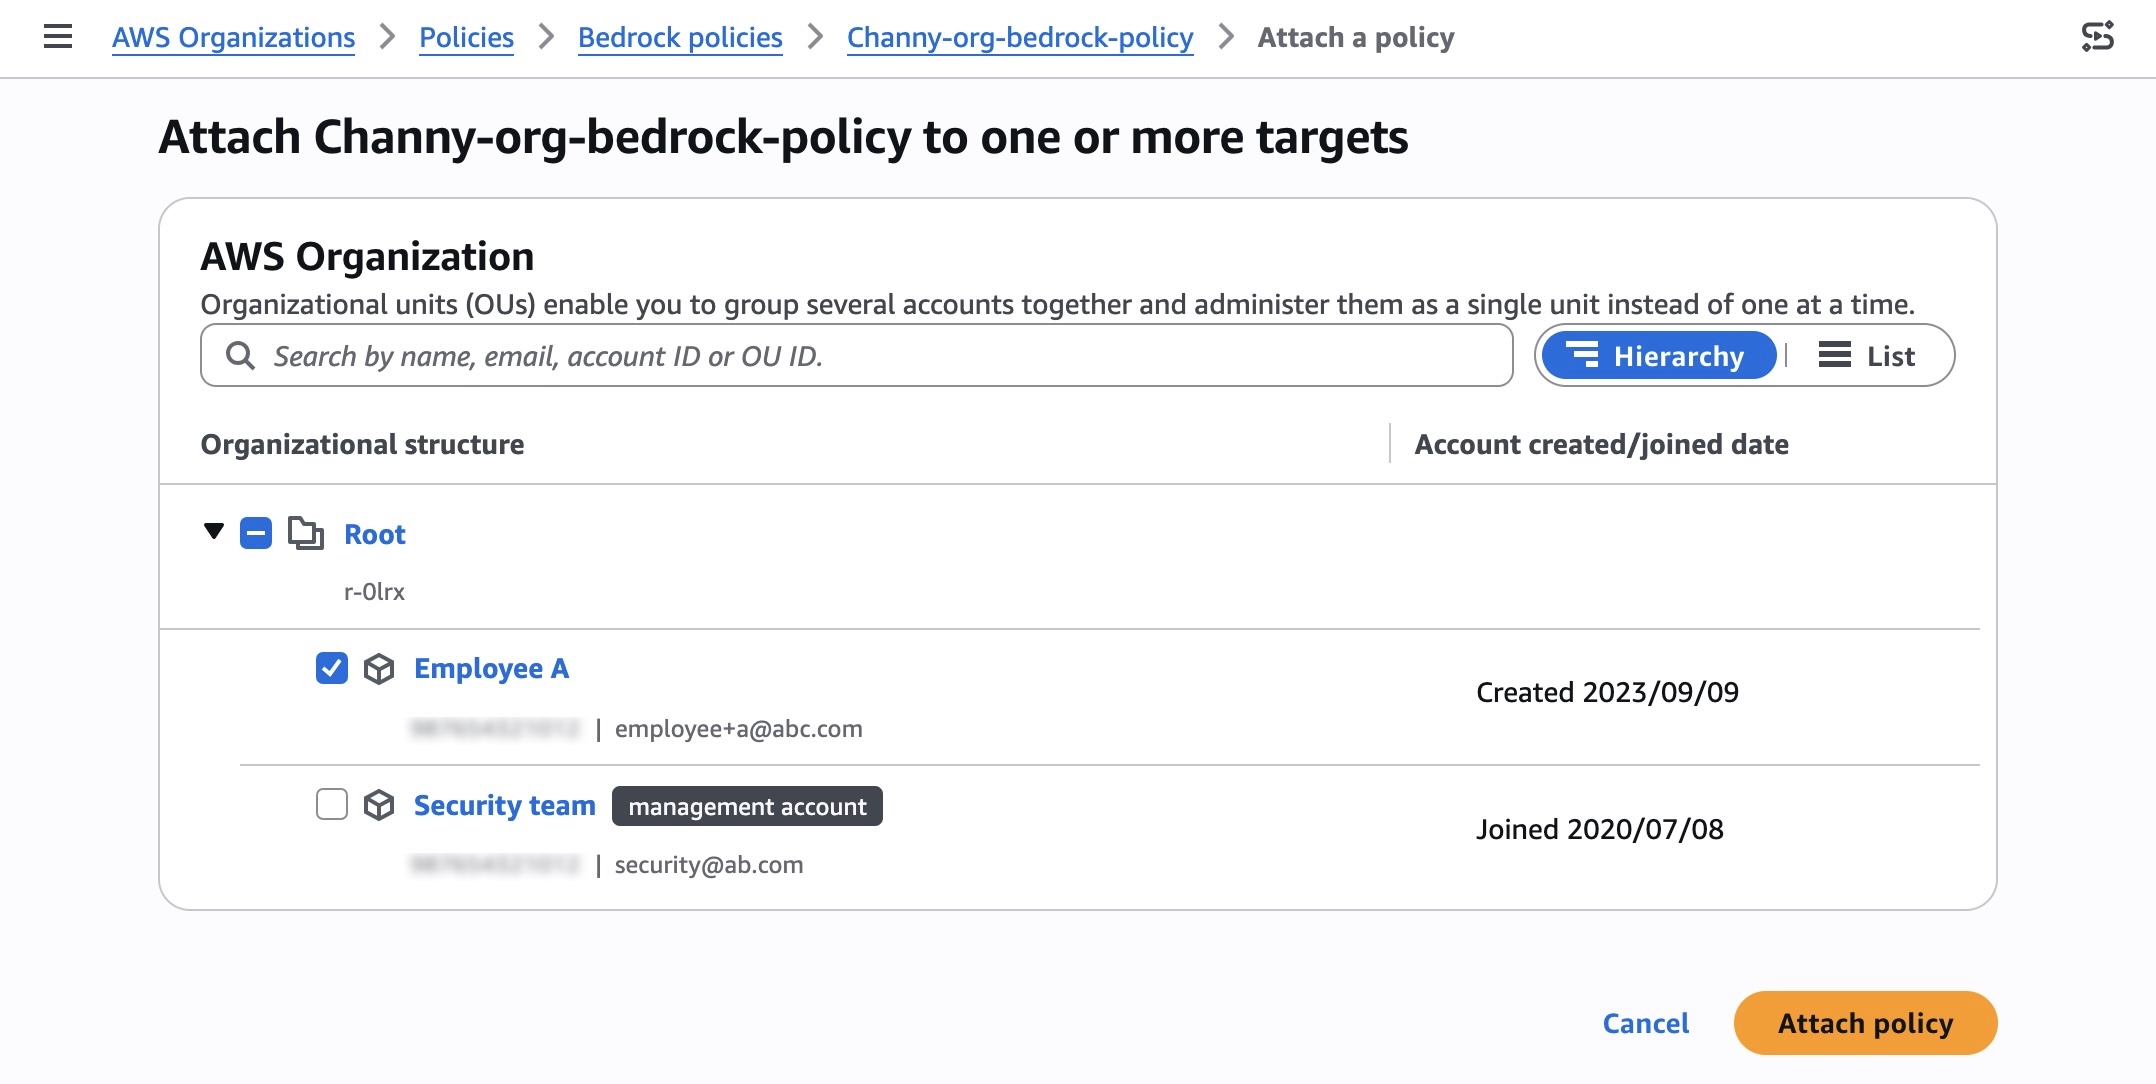
After creating the policy, you can attach the policy to your desired organizational units, accounts, root in the Targets tab.

Search and select your organization root, OUs, or individual accounts to attach your policy, and choose Attach policy.

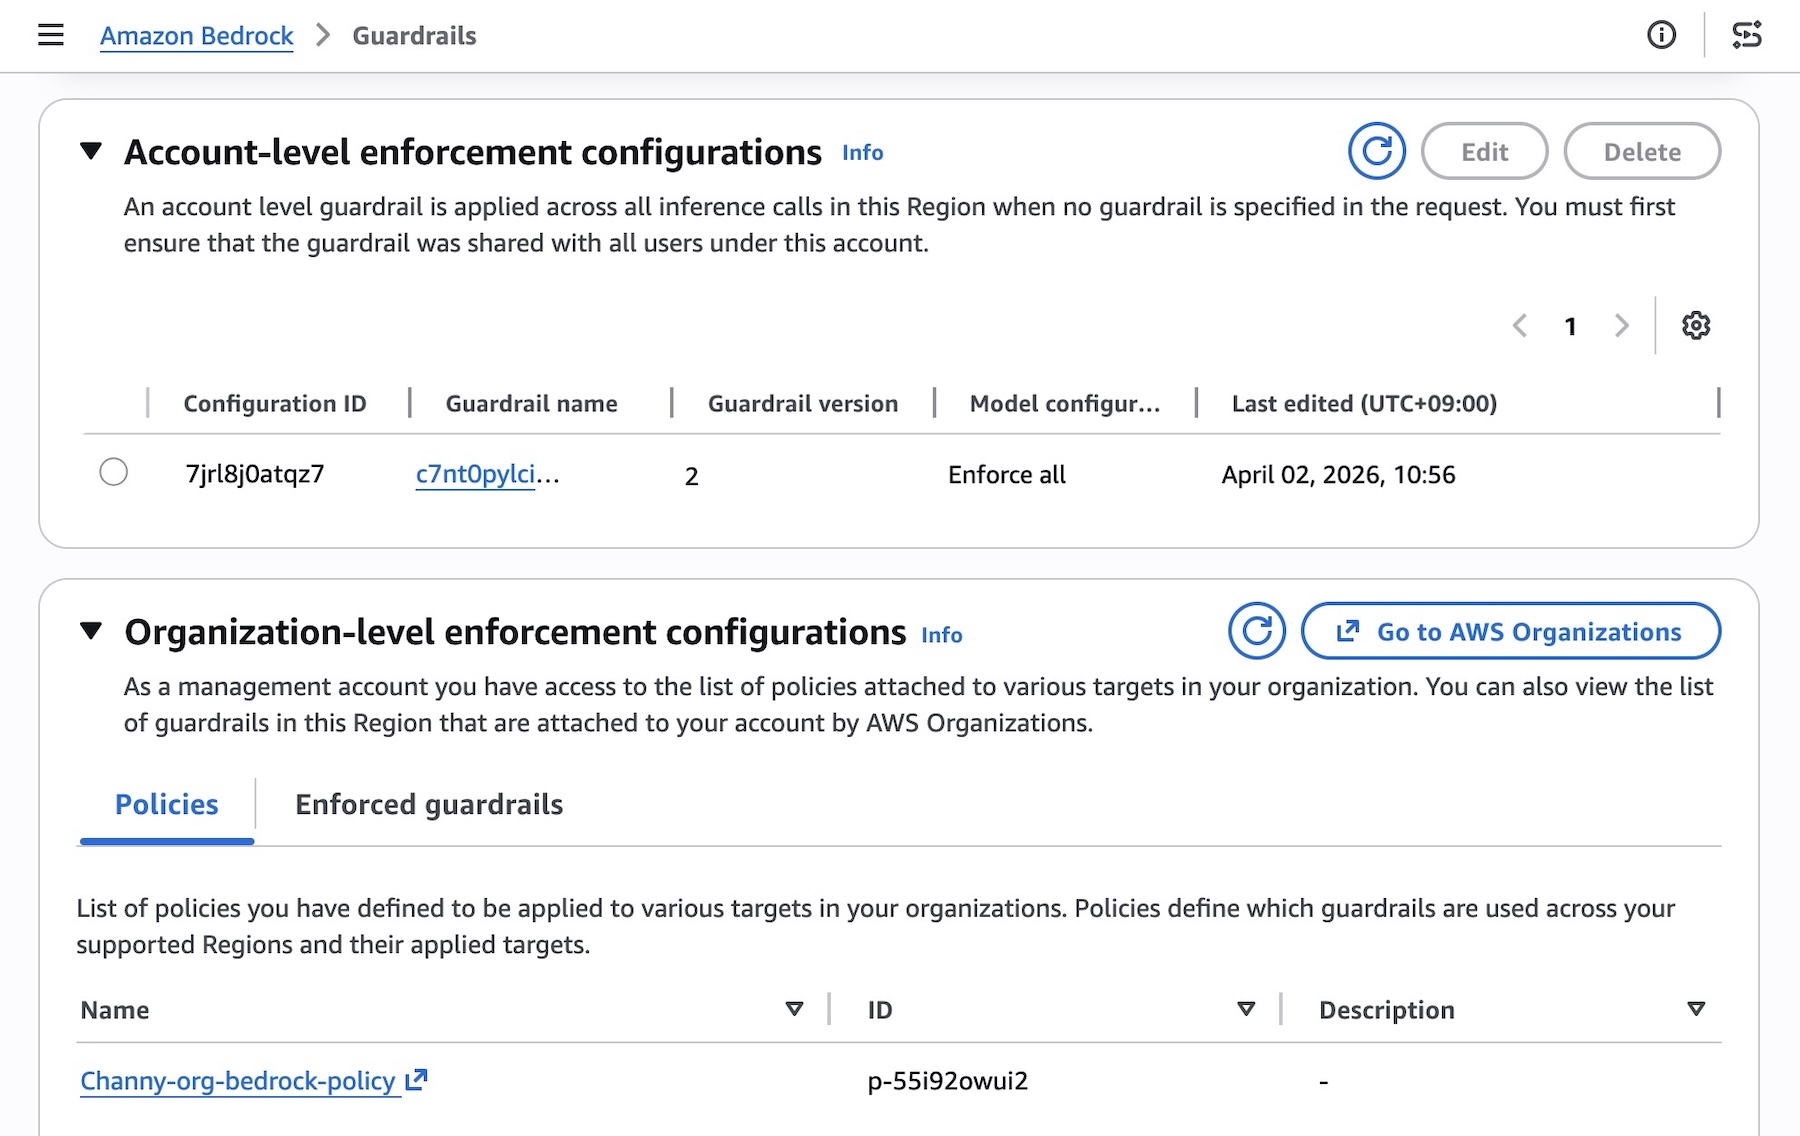
You can test that the guardrail is being enforced on member accounts and verify which guardrail is enforced. From a member account attached, you should see the organization enforced guardrail under the section Organization-level enforcement configurations.

The underlying safeguards within the specified guardrail are then automatically enforced for every model inference request across all member entities, ensuring consistent safety controls. To accommodate varying requirements of individual teams or applications, you can attach different policies with associated guardrails to different member entities through your organization.

Things to know
Here are key considerations to know about GA features:

  • You can now choose to include or exclude specific models in Bedrock for inference, enabling centralized enforcement on model invocation calls. You can also choose to safeguard partial or complete system prompts and input prompts. To learn more, visit Apply cross-account safeguards with Amazon Bedrock Guardrails enforcement.
  • Ensure you are specifying the accurate guardrail Amazon Resource Names (ARN) in the policy. Specifying an incorrect or invalid ARN will result in policy violations, non-enforcement of safeguards, and the inability to use the models in Amazon Bedrock for inference. To learn more, visit Best practices for using Amazon Bedrock policies.
  • Automated Reasoning checks are not supported with this capability.

Now available
Cross-account safeguards in Amazon Bedrock Guardrails is generally available today in the all AWS commercial and GovCloud Regions where Bedrock Guardrails is available. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. Charges apply to each enforced guardrail according to its configured safeguards. For detailed pricing information on individual safeguards, visit Amazon Bedrock Pricing page.

Give this capability a try in the Amazon Bedrock console and send feedback to AWS re:Post for Amazon Bedrock Guardrails or through your usual AWS Support contacts.

— Channy

Announcing managed daemon support for Amazon ECS Managed Instances

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/announcing-managed-daemon-support-for-amazon-ecs-managed-instances/

Today, we’re announcing managed daemon support for Amazon Elastic Container Service (Amazon ECS) Managed Instances. This new capability extends the managed instances experience we introduced in September 2025, by giving platform engineers independent control over software agents such as monitoring, logging, and tracing tools, without requiring coordination with application development teams, while also improving reliability by ensuring every instance consistently runs required daemons and enabling comprehensive host-level monitoring.

When running containerized workloads at scale, platform engineers manage a wide range of responsibilities, from scaling and patching infrastructure to keeping applications running reliably and maintaining the operational agents that support those applications. Until now, many of these concerns were tightly coupled. Updating a monitoring agent meant coordinating with application teams, modifying task definitions, and redeploying entire applications, a significant operational burden when you’re managing hundreds or thousands of services.

Decoupled lifecycle management for daemons

Amazon ECS now introduces a dedicated managed daemons construct that enables platform teams to centrally manage operational tooling. This separation of concerns allows platform engineers to independently deploy and update monitoring, logging, and tracing agents to infrastructure, while enforcing consistent use of required tools across all instances, without requiring application teams to redeploy their services. Daemons are guaranteed to start before application tasks and drain last, ensuring that logging, tracing, and monitoring are always available when your application needs them.

Platform engineers can deploy managed daemons across multiple capacity providers, or target specific capacity providers, giving them flexibility in how they roll out agents across their infrastructure. Resource management is also centralized, allowing teams to define daemon CPU and memory parameters separately from application configurations with no need to rebuild AMIs or update task definitions, while optimizing resource utilization since each instance runs exactly one daemon copy shared across multiple application tasks.

Let’s try it out
To take ECS Managed Daemons for a spin, I decided to start with the Amazon CloudWatch Agent as my first managed daemon. I had previously set up an Amazon ECS cluster with a Managed Instance capacity provider using the documentation.

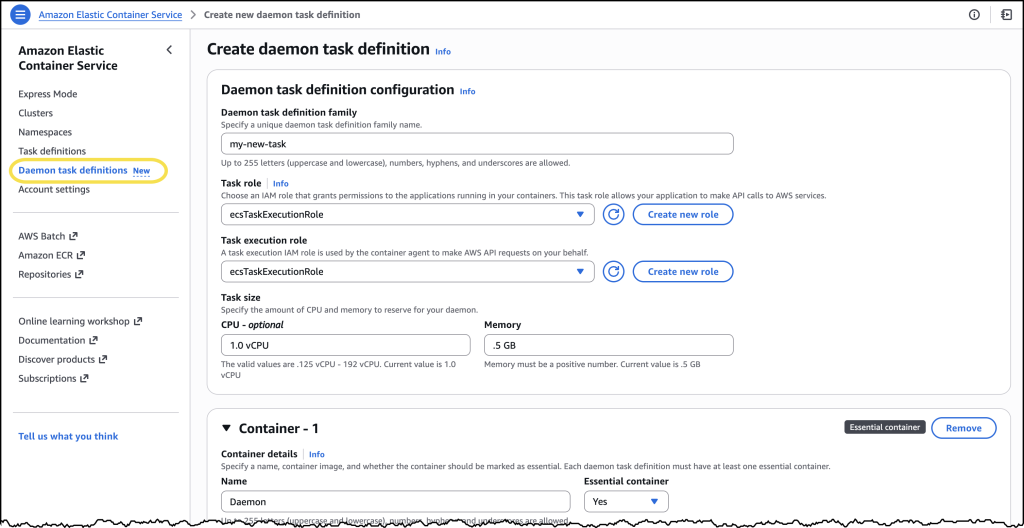
From the Amazon Elastic Container Service console, I noticed a new Daemon task definitions option in the navigation pane, where I can define my managed daemons.

Managed daemons console

I chose Create new daemon task definition to get started. For this example, I configured the CloudWatch Agent with 1 vCPU and 0.5 GB of memory. In the Daemon task definition family field, I entered a name I’d recognize later.

For the Task execution role, I selected ecsTaskExecutionRole from the dropdown. Under the Container section, I gave my container a descriptive name and pasted in the image URI: public.ecr.aws/cloudwatch-agent/cloudwatch-agent:latest along with a few additional details.

After reviewing everything, I chose Create.

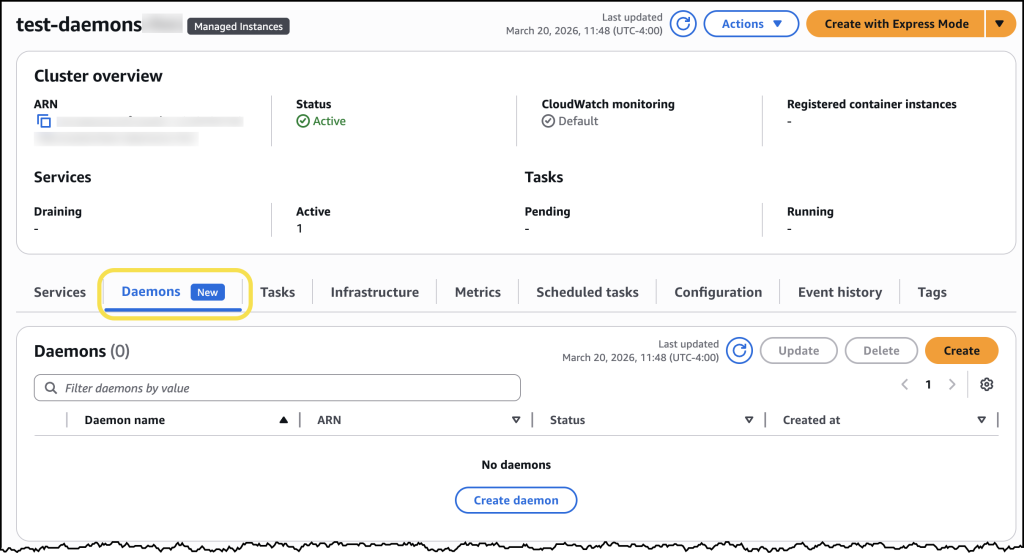
Once my daemon task definition was created, I navigated to the Clusters page, selected my previously created cluster and found the new Daemons tab.

Managed daemons 2

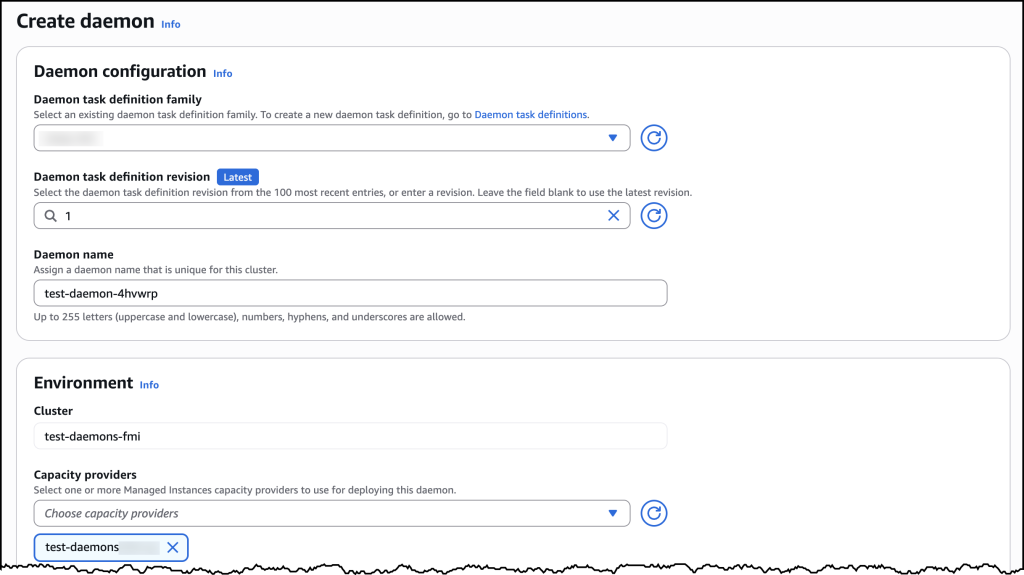
Here I can simply click the Create daemon button and complete the form to configure my daemon.

Managed daemons 3

Under Daemon configuration, I selected my newly created daemon task definition family and then assigned my daemon a name. For Environment configuration, I selected the ECS Managed Instances capacity provider I had set up earlier. After confirming my settings, I chose Create.

Now ECS automatically ensures the daemon task launches first on every provisioned ECS managed instance in my selected capacity provider. To see this in action, I deployed a sample nginx web service as a test workload. Once my workload was deployed, I could see in the console that ECS Managed Daemons had automatically deployed the CloudWatch Agent daemon alongside my application, with no manual intervention required.

When I later updated my daemon, ECS handled the rolling deployment automatically by provisioning new instances with the updated daemon, starting the daemon first, then migrating application tasks to the new instances before terminating the old ones. This “start before stop” approach ensures continuous daemon coverage: your logging, monitoring, and tracing agents remain operational throughout the update with no gaps in data collection. The drain percentage I configured controlled the pace of this replacement, giving me complete control over addon updates without any application downtime.

How it works
The managed daemon experience introduces a new daemon task definition that is separate from task definitions, with its own parameters and validation scheme. A new daemon_bridge network mode enables daemons to communicate with application tasks while remaining isolated from application networking configurations.

Managed daemons support advanced host-level access capabilities that are essential for operational tooling. Platform engineers can configure daemon tasks as privileged containers, add additional Linux capabilities, and mount paths from the underlying host filesystem. These capabilities are particularly valuable for monitoring and security agents that require deep visibility into host-level metrics, processes, and system calls.

When a daemon is deployed, ECS launches exactly one daemon process per container instance before placing application tasks. This guarantees that operational tooling is in place before your application starts receiving traffic. ECS also supports rolling deployments with automatic rollbacks, so you can update agents with confidence.

Now available
Managed daemon support for Amazon ECS Managed Instances is available today in all AWS Regions. To get started, visit the Amazon ECS console or review the Amazon ECS documentation. You can also explore the new managed daemons Application Programming Interface (APIs) by visiting this website.

There is no additional cost to use managed daemons. You pay only for the standard compute resources consumed by your daemon tasks.

Announcing the AWS Sustainability console: Programmatic access, configurable CSV reports, and Scope 1–3 reporting in one place

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/announcing-the-aws-sustainability-console-programmatic-access-configurable-csv-reports-and-scope-1-3-reporting-in-one-place/

As many of you are, I’m a parent. And like you, I think about the world I’m building for my children. That’s part of why today’s launch matters for many of us. I’m excited to announce the launch of the AWS Sustainability console, a standalone service that consolidates all AWS sustainability reporting and resources in one place.

With the The Climate Pledge, Amazon set a goal in 2019 to reach net-zero carbon across our operations by 2040. That commitment shapes how AWS builds its data centers and services. In addition, AWS is also committed to helping you measure and reduce the environmental footprint of your own workloads. The AWS Sustainability console is the latest step in that direction.

The AWS Sustainability console builds on the Customer Carbon Footprint Tool (CCFT), which lives inside the AWS Billing console, and introduces a new set of capabilities for which you’ve been asking.

Until now, accessing your carbon footprint data required billing-level permissions. That created a practical problem: sustainability professionals and reporting teams often don’t have (and shouldn’t need) access to cost and billing data. Getting the right people access to the right data meant navigating permission structures that weren’t designed with sustainability workflows in mind. The AWS Sustainability console has its own permissions model, independent of the Billing console. Sustainability professionals can now get direct access to emissions data without requiring billing permissions to be granted alongside it.

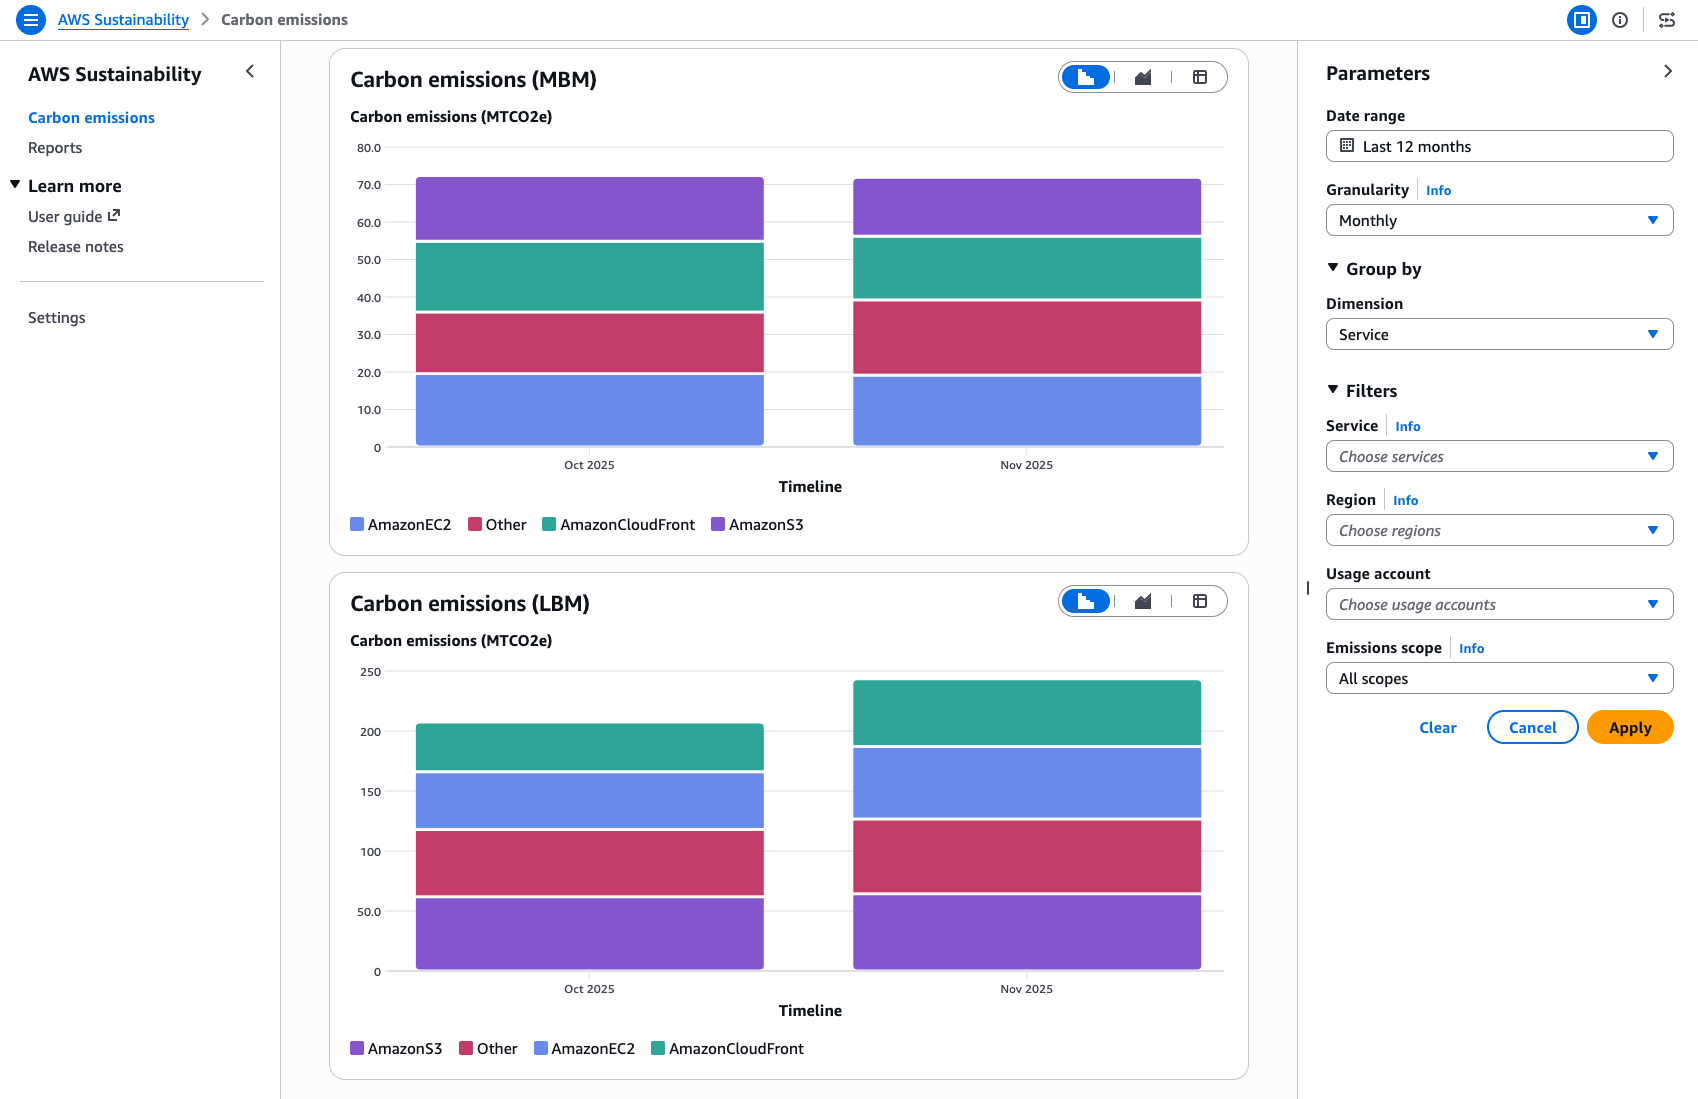
The console includes Scope 1, 2, and 3 emissions attributed to your AWS usage and shows you a breakdown by AWS Region, service, such as Amazon CloudFront, Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Simple Storage Service (Amazon S3). The underlying data and methodology haven’t changed with this launch; these are the same as the ones used by the CCFT. We changed how you can access and work with the data.

As sustainability reporting requirements have grown more complex, teams need more flexibility accessing and working with their emissions data. The console now includes a Reports page where you can download preset monthly and annual carbon emissions reports covering both market-based method (MBM) and location-based method (LBM) data. You can also build a custom comma-separated values (CSV) report by selecting which fields to include, the time granularity, and other filters.

If your organization’s fiscal year doesn’t align with the calendar year, you can now configure the console to match your reporting period. When that is set, all data views and exports reflect your fiscal year and quarters, which removes a common friction point for finance and sustainability teams working in parallel.

You can also use the new API or the AWS SDKs to integrate emissions data into your own reporting pipelines, dashboards, or compliance workflows. This is useful for teams that need to pull data for a specific month across a large number of accounts without setting up a data export or for organizations that need to establish custom account groupings that don’t align with their existing AWS Organizations structure.

You can read about the latest features released and methodology updates directly on the Release notes page on the Learn more tab.

Lets see it in action
To show you the Sustainability console, I opened the AWS Management Console and searched for “sustainability” in the search bar at the top of the screen.

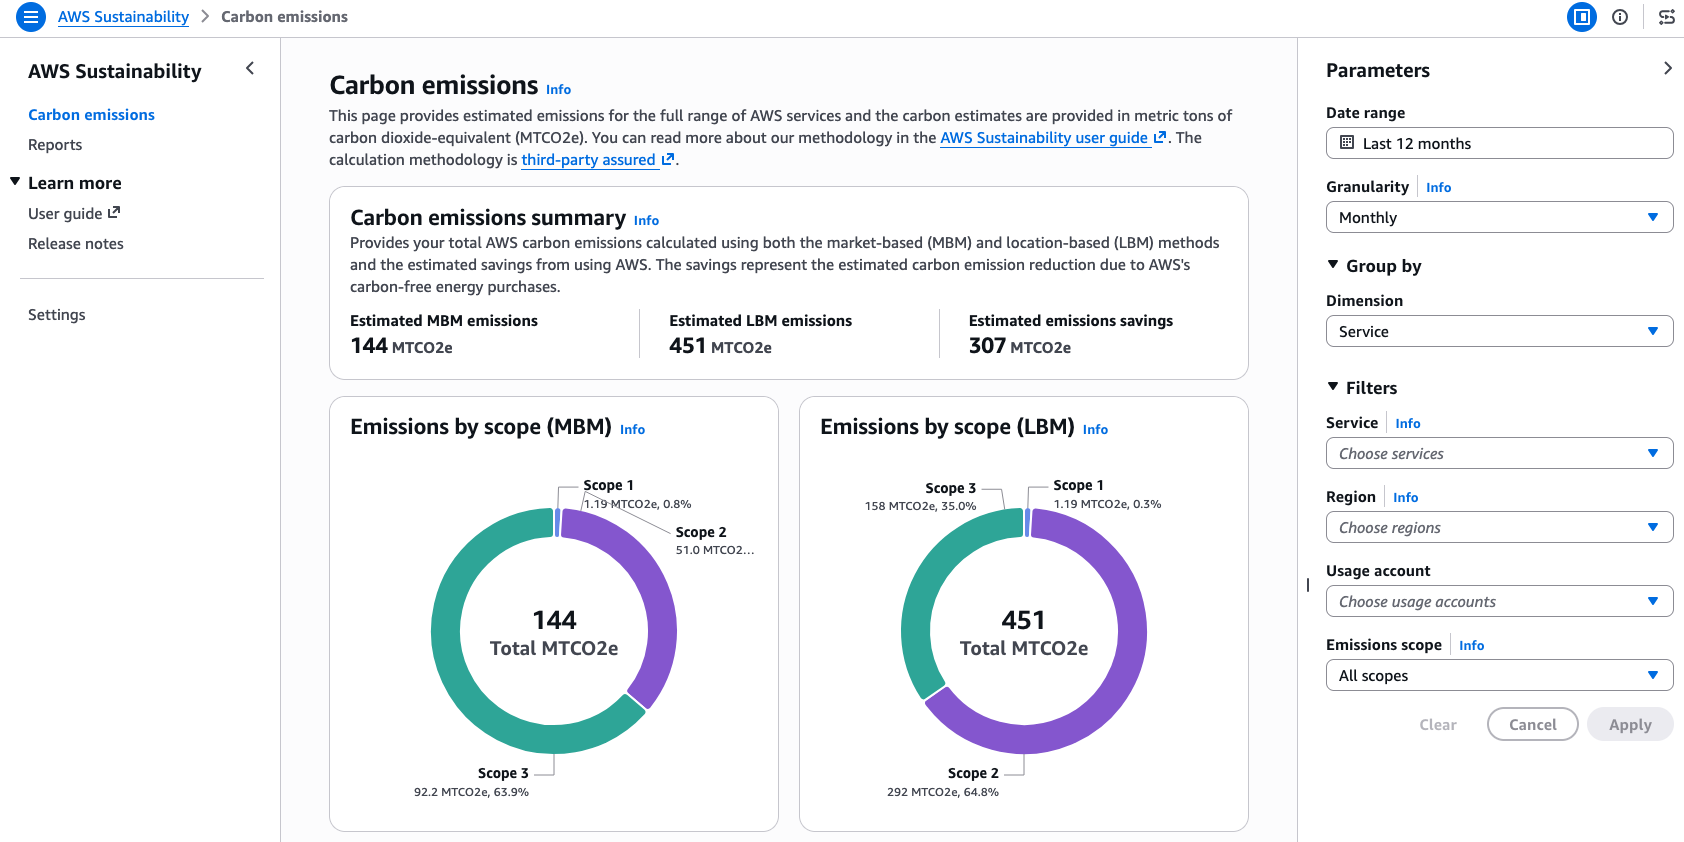
Sustainability console - carbon emission 1

Sustainability console - carbon emission 2

The Carbon emissions section gives an estimate on your carbon emissions, expressed in metric tons of carbon dioxide equivalent (MTCO2e). It shows the emissions by scope, expressed in the MBM and the LBM. On the right side of the screen, you can adjust the date range or filter by service, Regions, and more.

For those unfamiliar: Scope 1 includes direct emissions from owned or controlled sources (for example, data center fuel use); Scope 2 covers indirect emissions from the production of purchased energy (with MBM accounting for energy attribute certificates and LBM using average local grid emissions); and Scope 3 includes other indirect emissions across the value chain, such as server manufacturing and data center construction. You can read more about this in our methodology document, which was independently verified by Apex, a third-party consultant.

I can also use API or AWS Command Line Interface (AWS CLI) to programmatically pull the emissions data.

aws sustainability get-estimated-carbon-emissions \
     --time-period='{"Start":"2025-03-01T00:00:00Z","End":"2026-03-01T23:59:59.999Z"}'

{
    "Results": [
        {
            "TimePeriod": {
                "Start": "2025-03-01T00:00:00+00:00",
                "End": "2025-04-01T00:00:00+00:00"
            },
            "DimensionsValues": {},
            "ModelVersion": "v3.0.0",
            "EmissionsValues": {
                "TOTAL_LBM_CARBON_EMISSIONS": {
                    "Value": 0.7,
                    "Unit": "MTCO2e"
                },
                "TOTAL_MBM_CARBON_EMISSIONS": {
                    "Value": 0.1,
                    "Unit": "MTCO2e"
                }
            }
        },
...

The combination of the visual console and the new API gives you two additional ways to work with your data, in addition to the Data Exports still available. You can now explore and identify hotspots on the console and automate the reporting you want to share with stakeholders.

The Sustainability console is designed to grow. We plan to continue to release new features as we grow the console’s capabilities alongside our customers.

Get started today
The AWS Sustainability console is available today at no additional cost. You can access it from the AWS Management Console. Historical data is available going back to January 2022, so you can start exploring your emissions trends right away.

Get started on the console today. If you want to learn more about the AWS commitment to sustainability, visit the AWS Sustainability page.

— seb
Customize your AWS Management Console experience with visual settings including account color, region and service visibility

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/customize-your-aws-management-console-experience-with-visual-settings-including-account-color-region-and-service-visibility/

In August 2025, we introduced AWS User Experience Customization (UXC) capability to tailor user interfaces (UIs) to meet your specific needs and complete your tasks efficiently. With this capability, your account administrator can customize some UI component of AWS Management Console, such as assigning a color to an AWS account for easier identification.

Today, we’re announcing additional customization capability in UXC that enables selective display of relevant AWS Regions and services for your team members. By hiding unused Regions and services, you can reduce cognitive load and eliminate unnecessary clicks and scrolling, helping you focus better and work faster. With this launch, we offer the ability to customize account color, Region, and service visibility together.

Categorize account by color
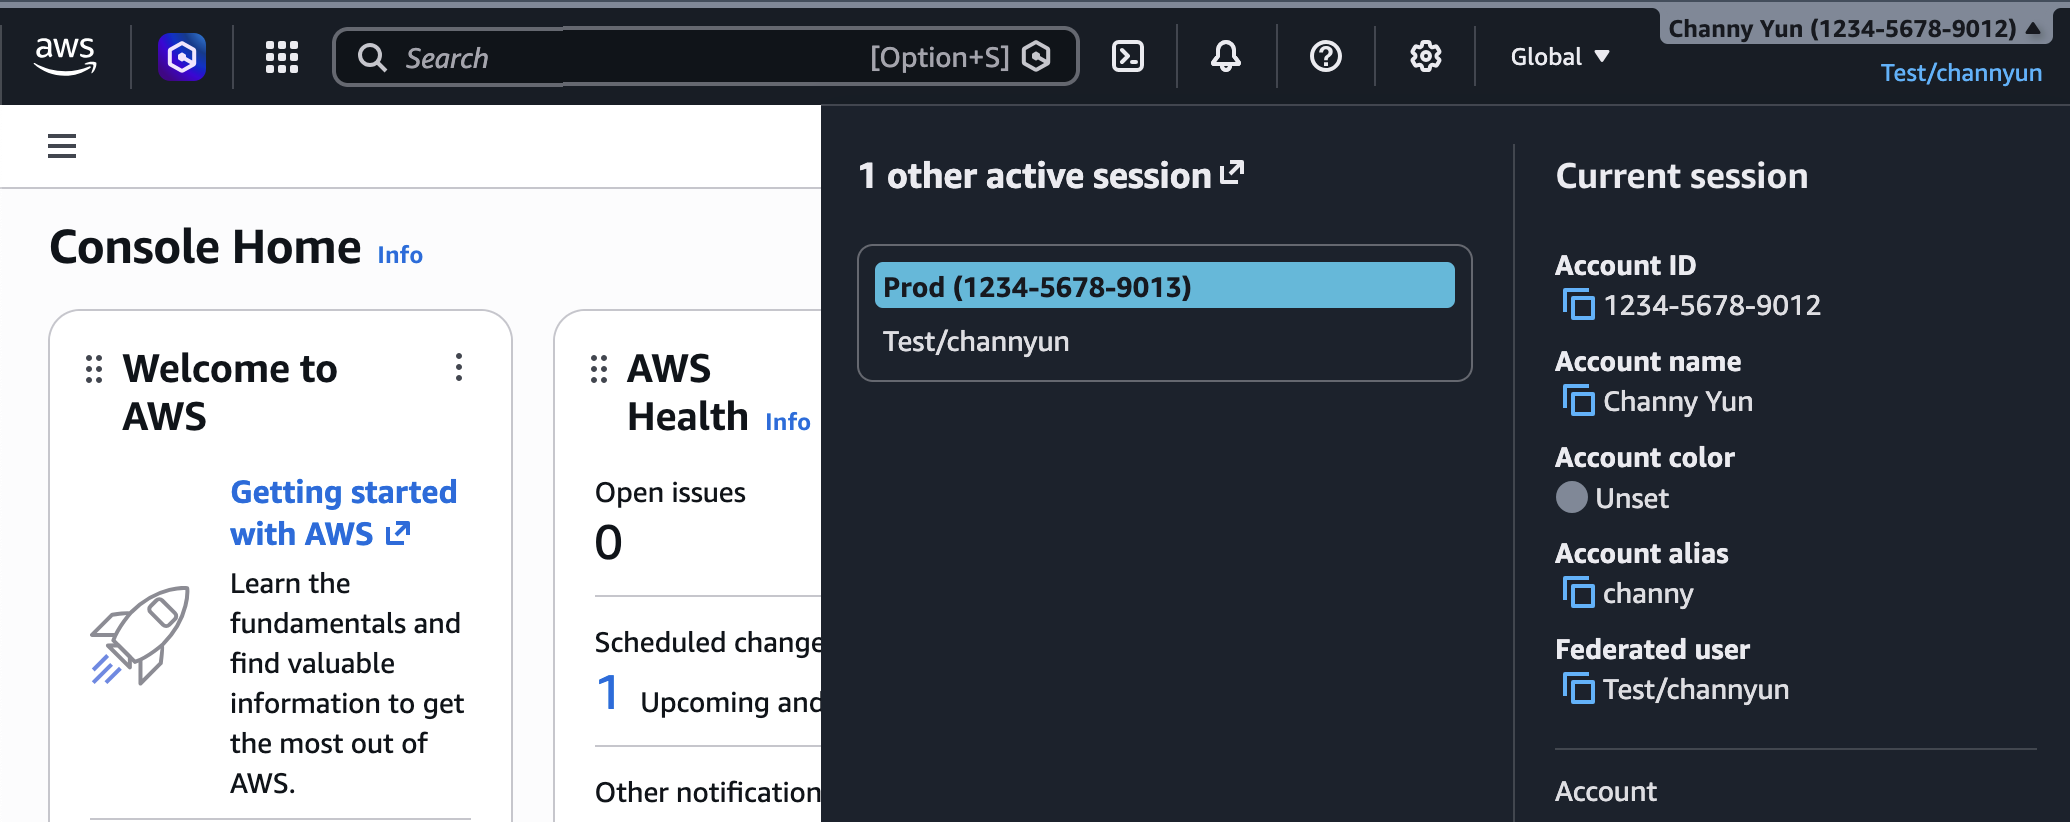
You can set a color for your accounts to visually distinguish between them. To get started, sign in to the AWS Management Console and choose your account name on the navigation bar. Your account color isn’t set yet. To set the color, choose Account.

In the Account display settings, select your preferred account color and choose Update. You can see the chosen color in the navigation bar.

By changing the account color, you can clearly distinguish the account’s purpose. For example, you can use orange for development accounts, light blue for test accounts, and red for production accounts.

Customize Regions and services visibility
You can control which AWS Regions appear in the Region selector or which AWS services appear in the console navigation. In other words, you can set to show only the Regions and services that are relevant to your account.

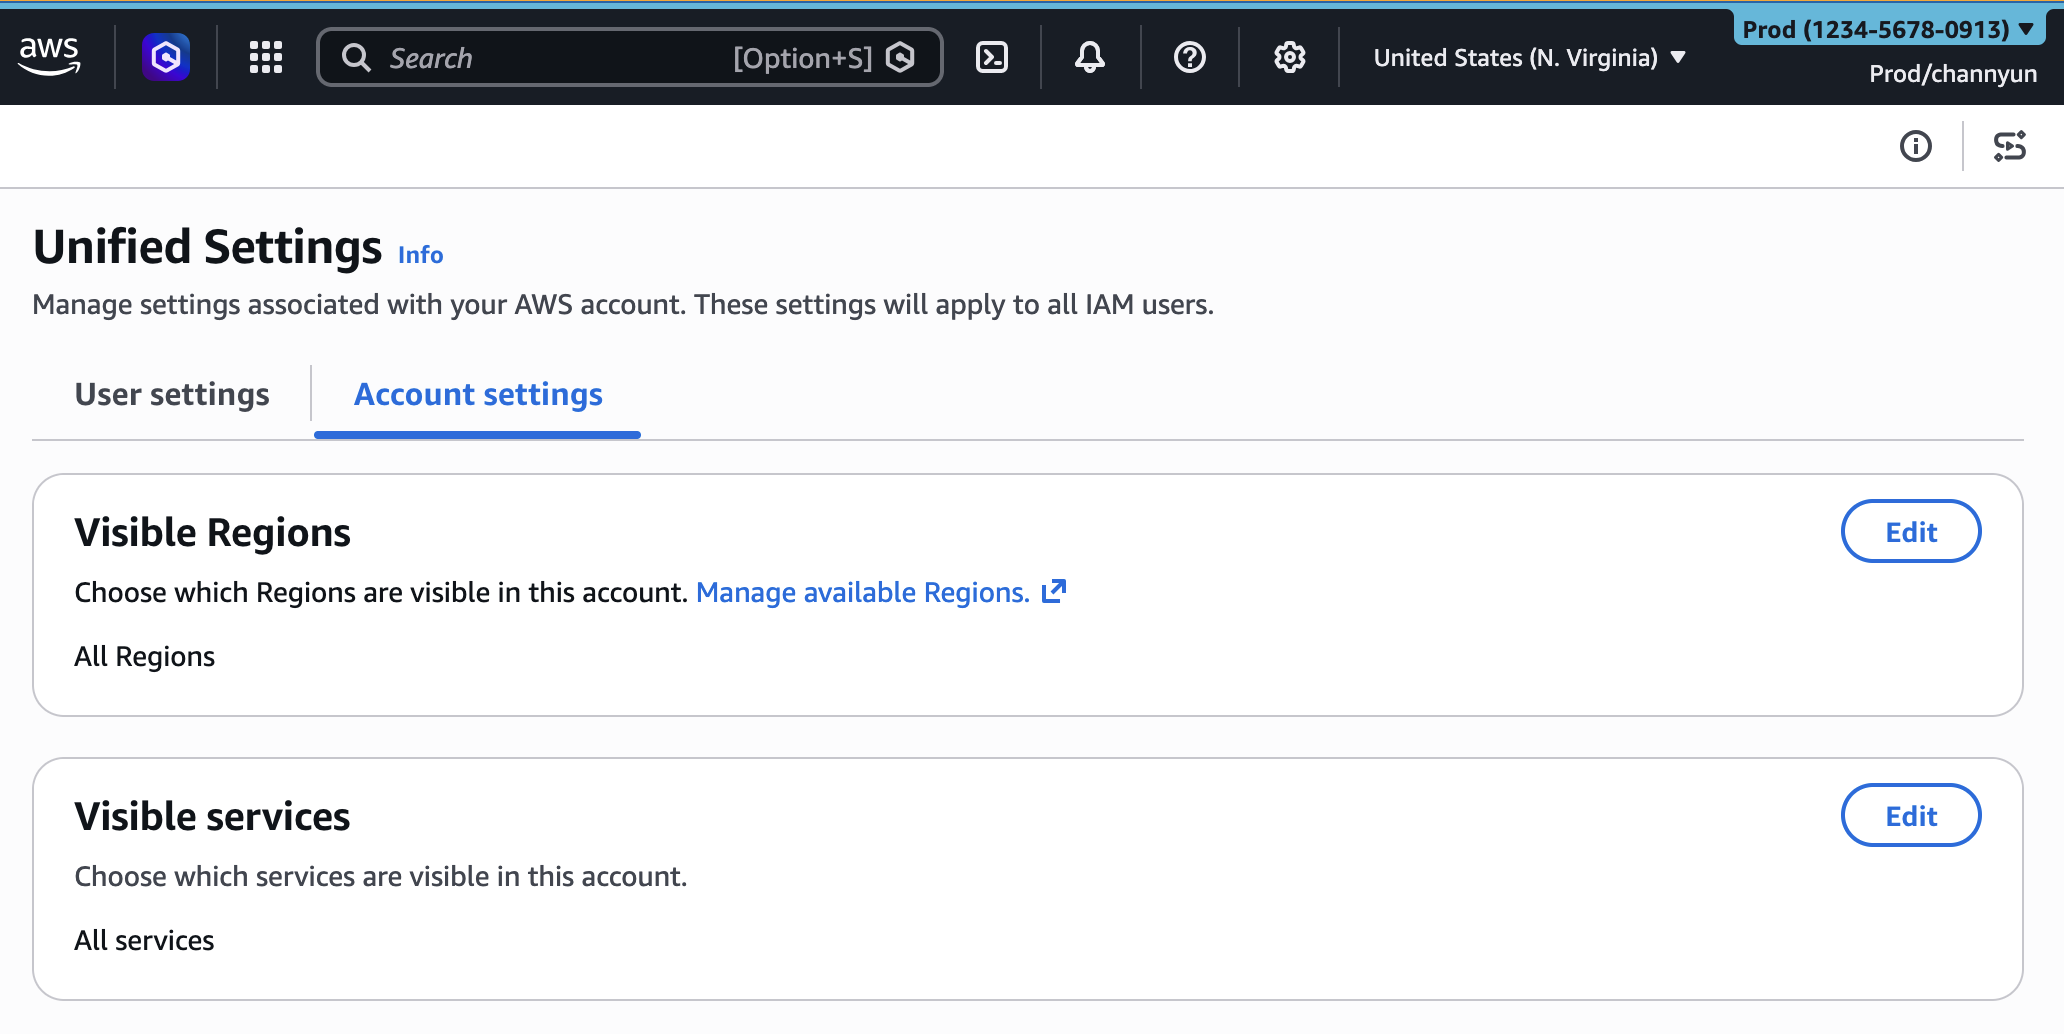
To get started, choose the gear icon on the navigation bar and choose See all user settings. If you are in an administrator role, you can see a new Account settings tab in the unified settings. If you have not configured a setting, all Regions and services are visible.

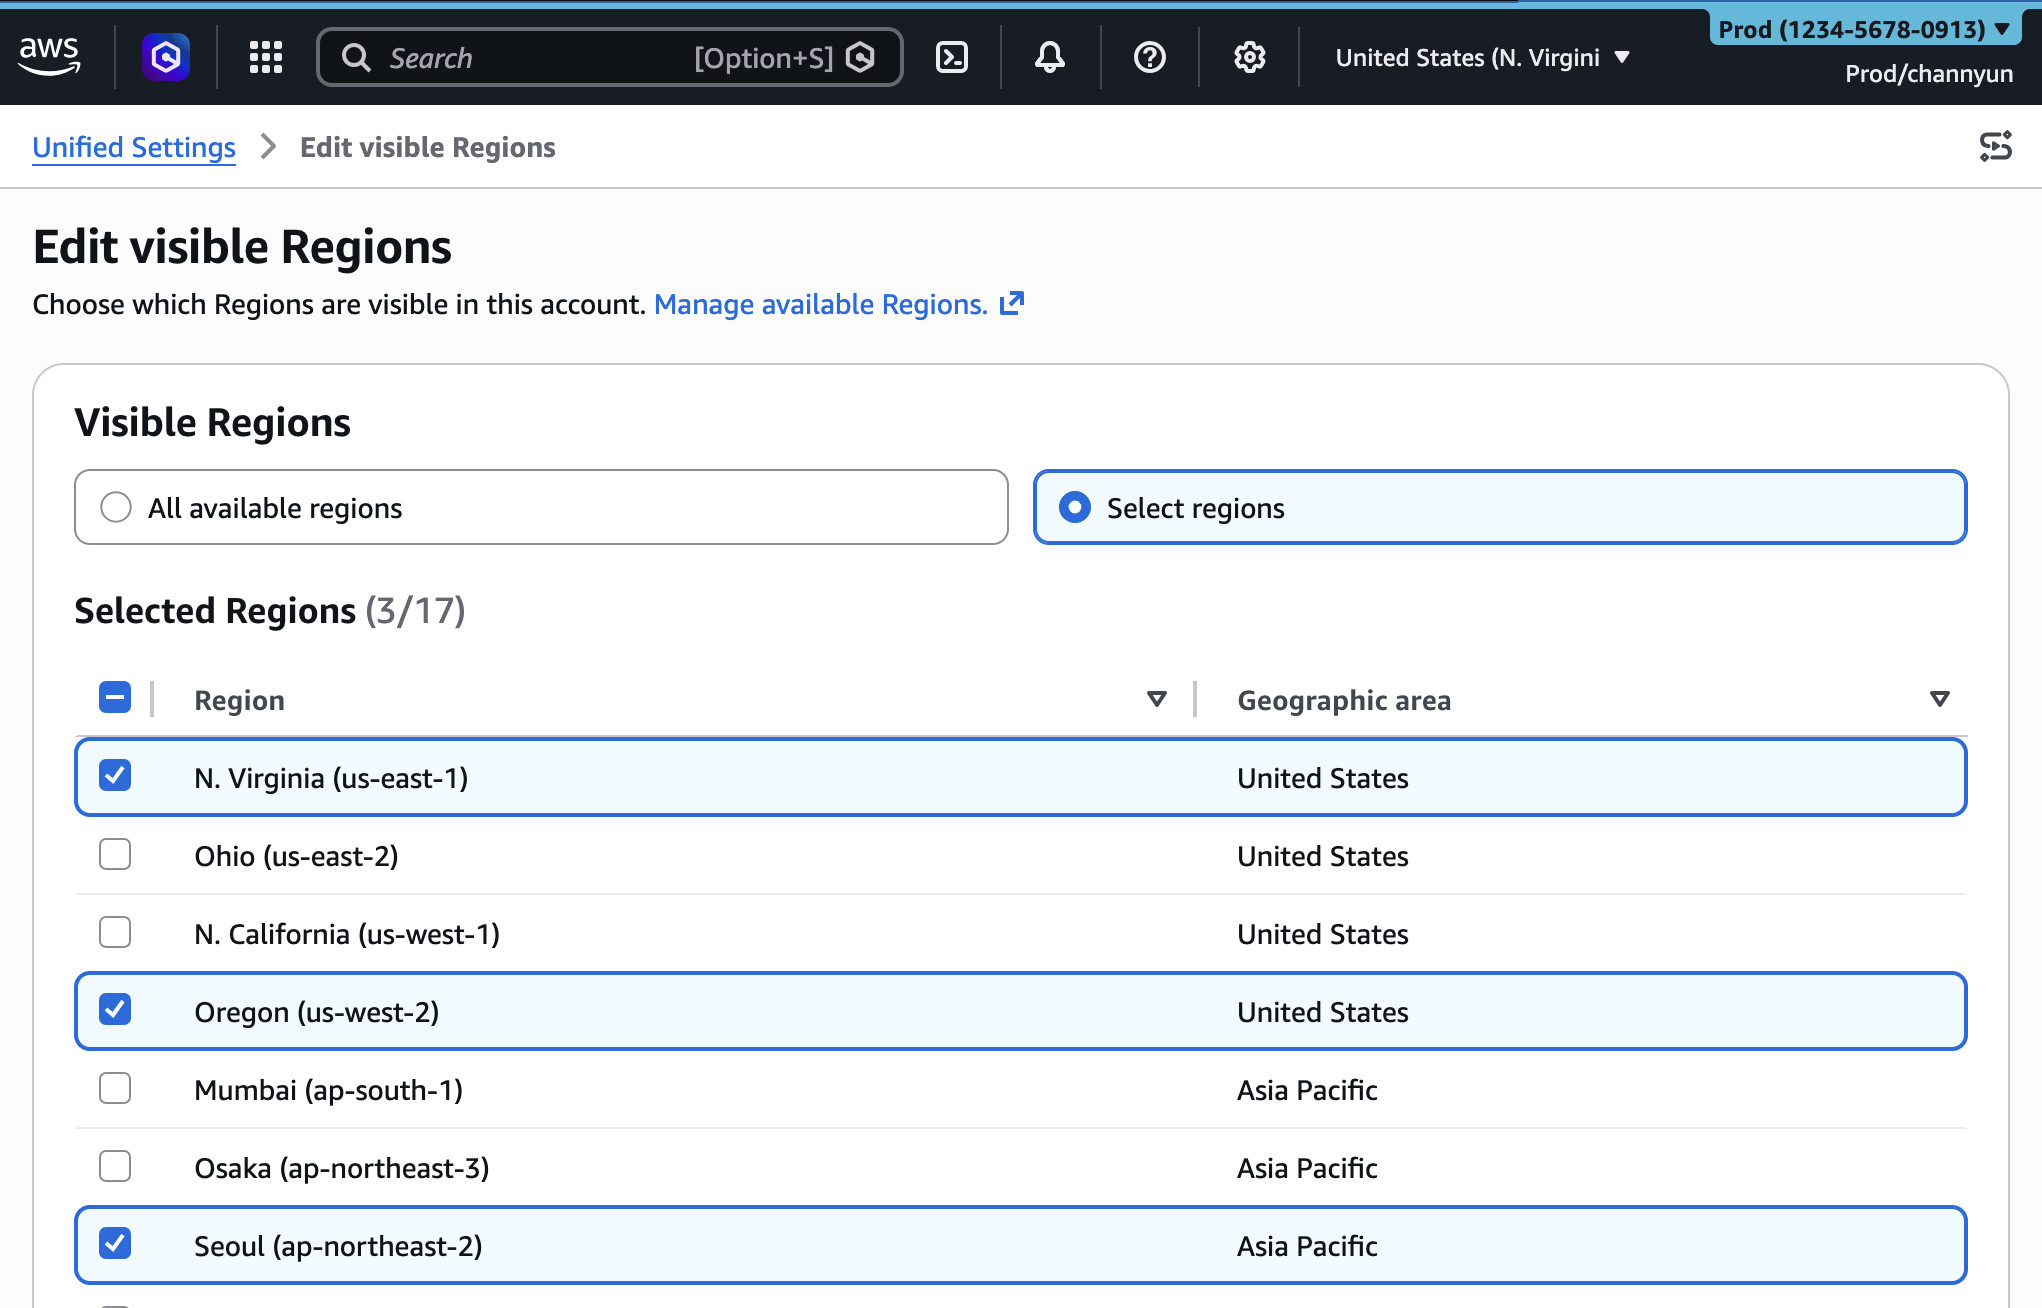
To set visible Regions, choose Edit in the Visible Regions section. Select your visible Regions to All available Regions or Select Regions and configure your list. Choose Save changes.

After configuring visible Region setting, you will find only selected Regions in the Regions selector on the navigation bar in the console.

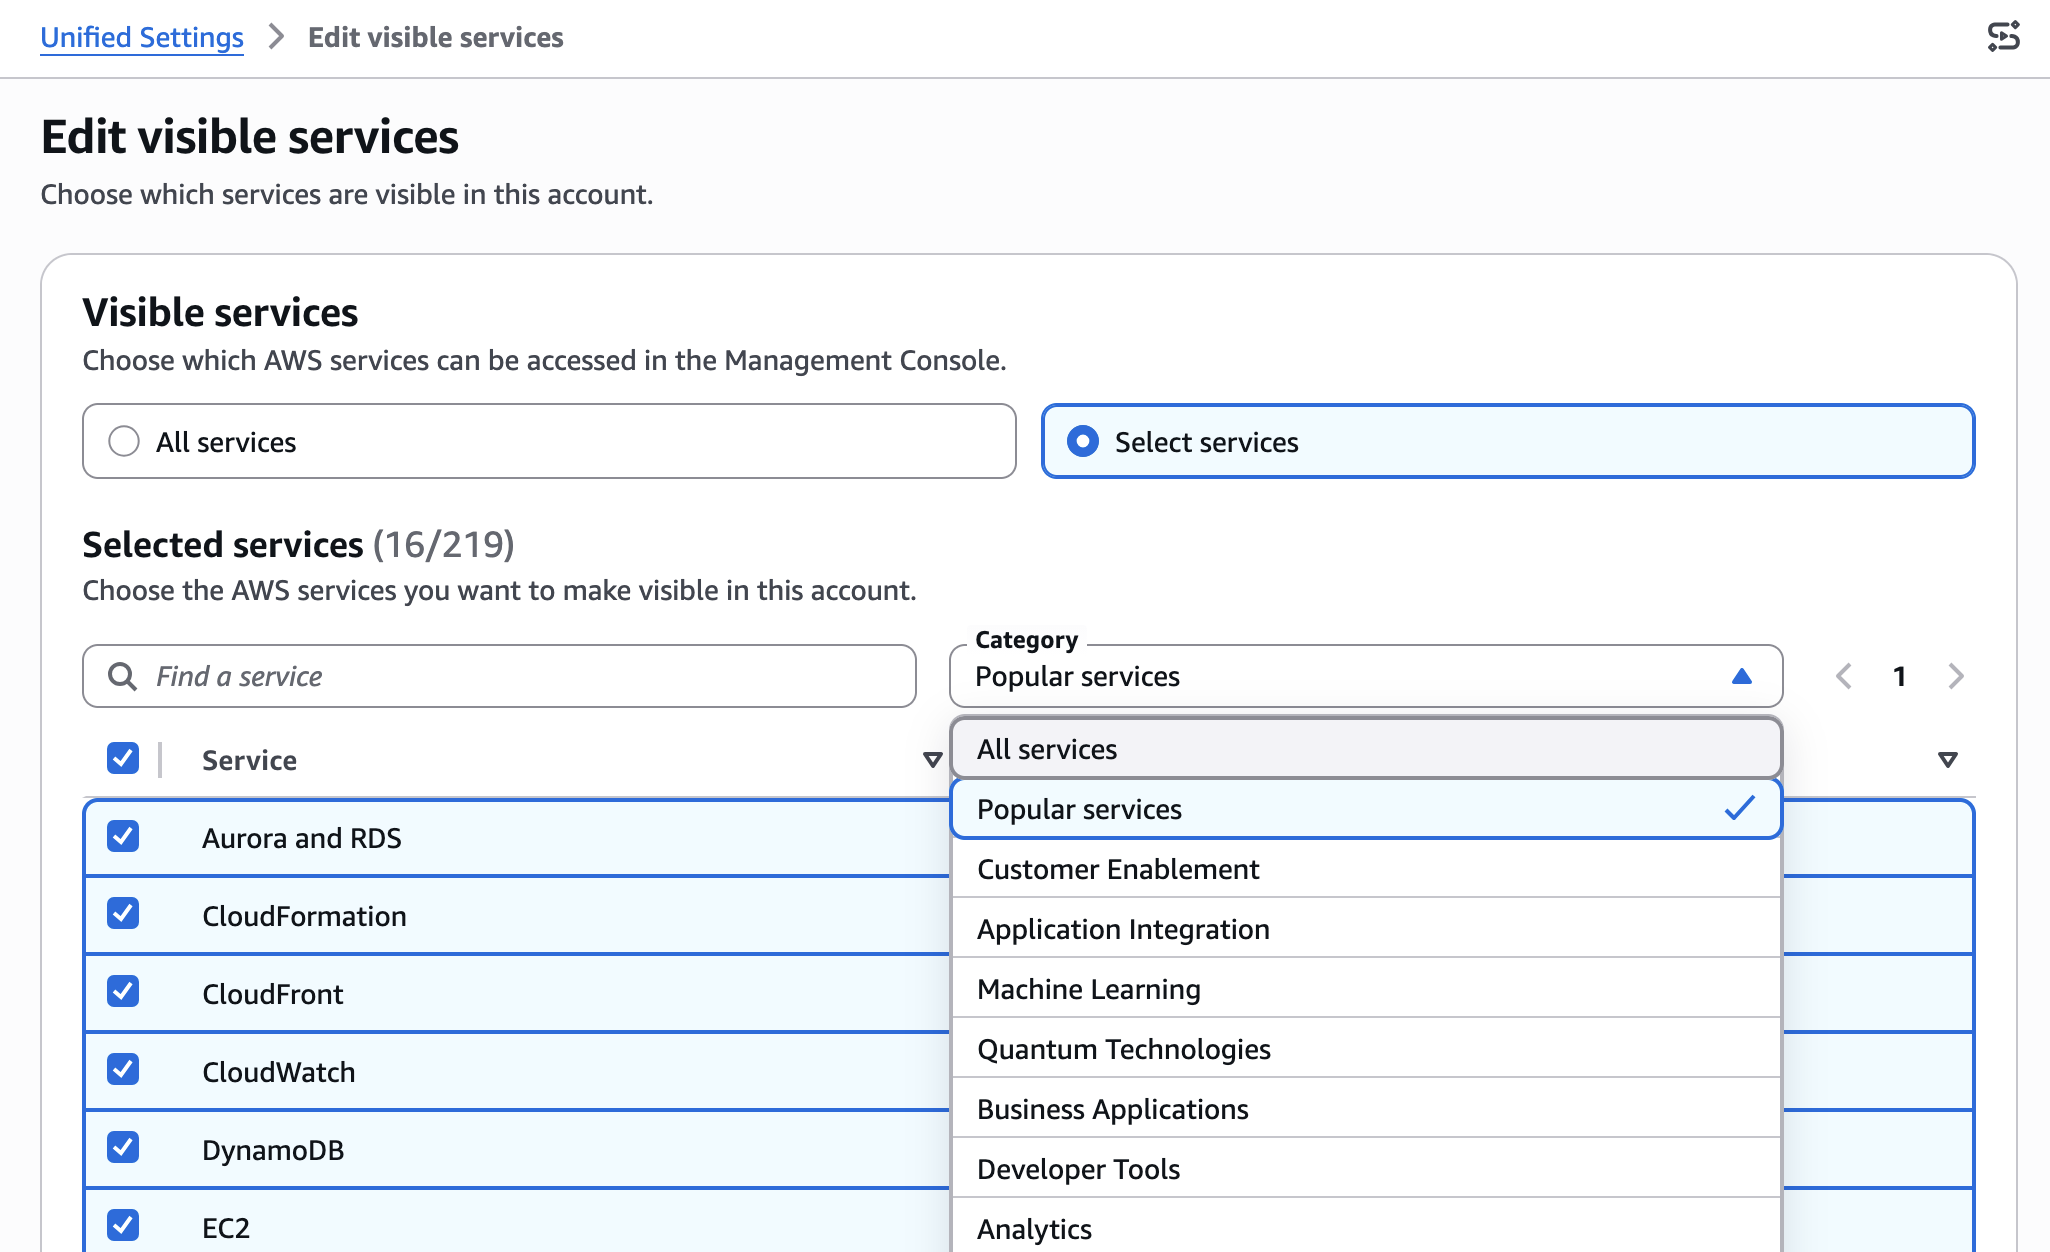
You can also set visible services in the same way. Search or select services from the category. I used the Popular services category to select my favorites. When you finish selection, choose Save changes.

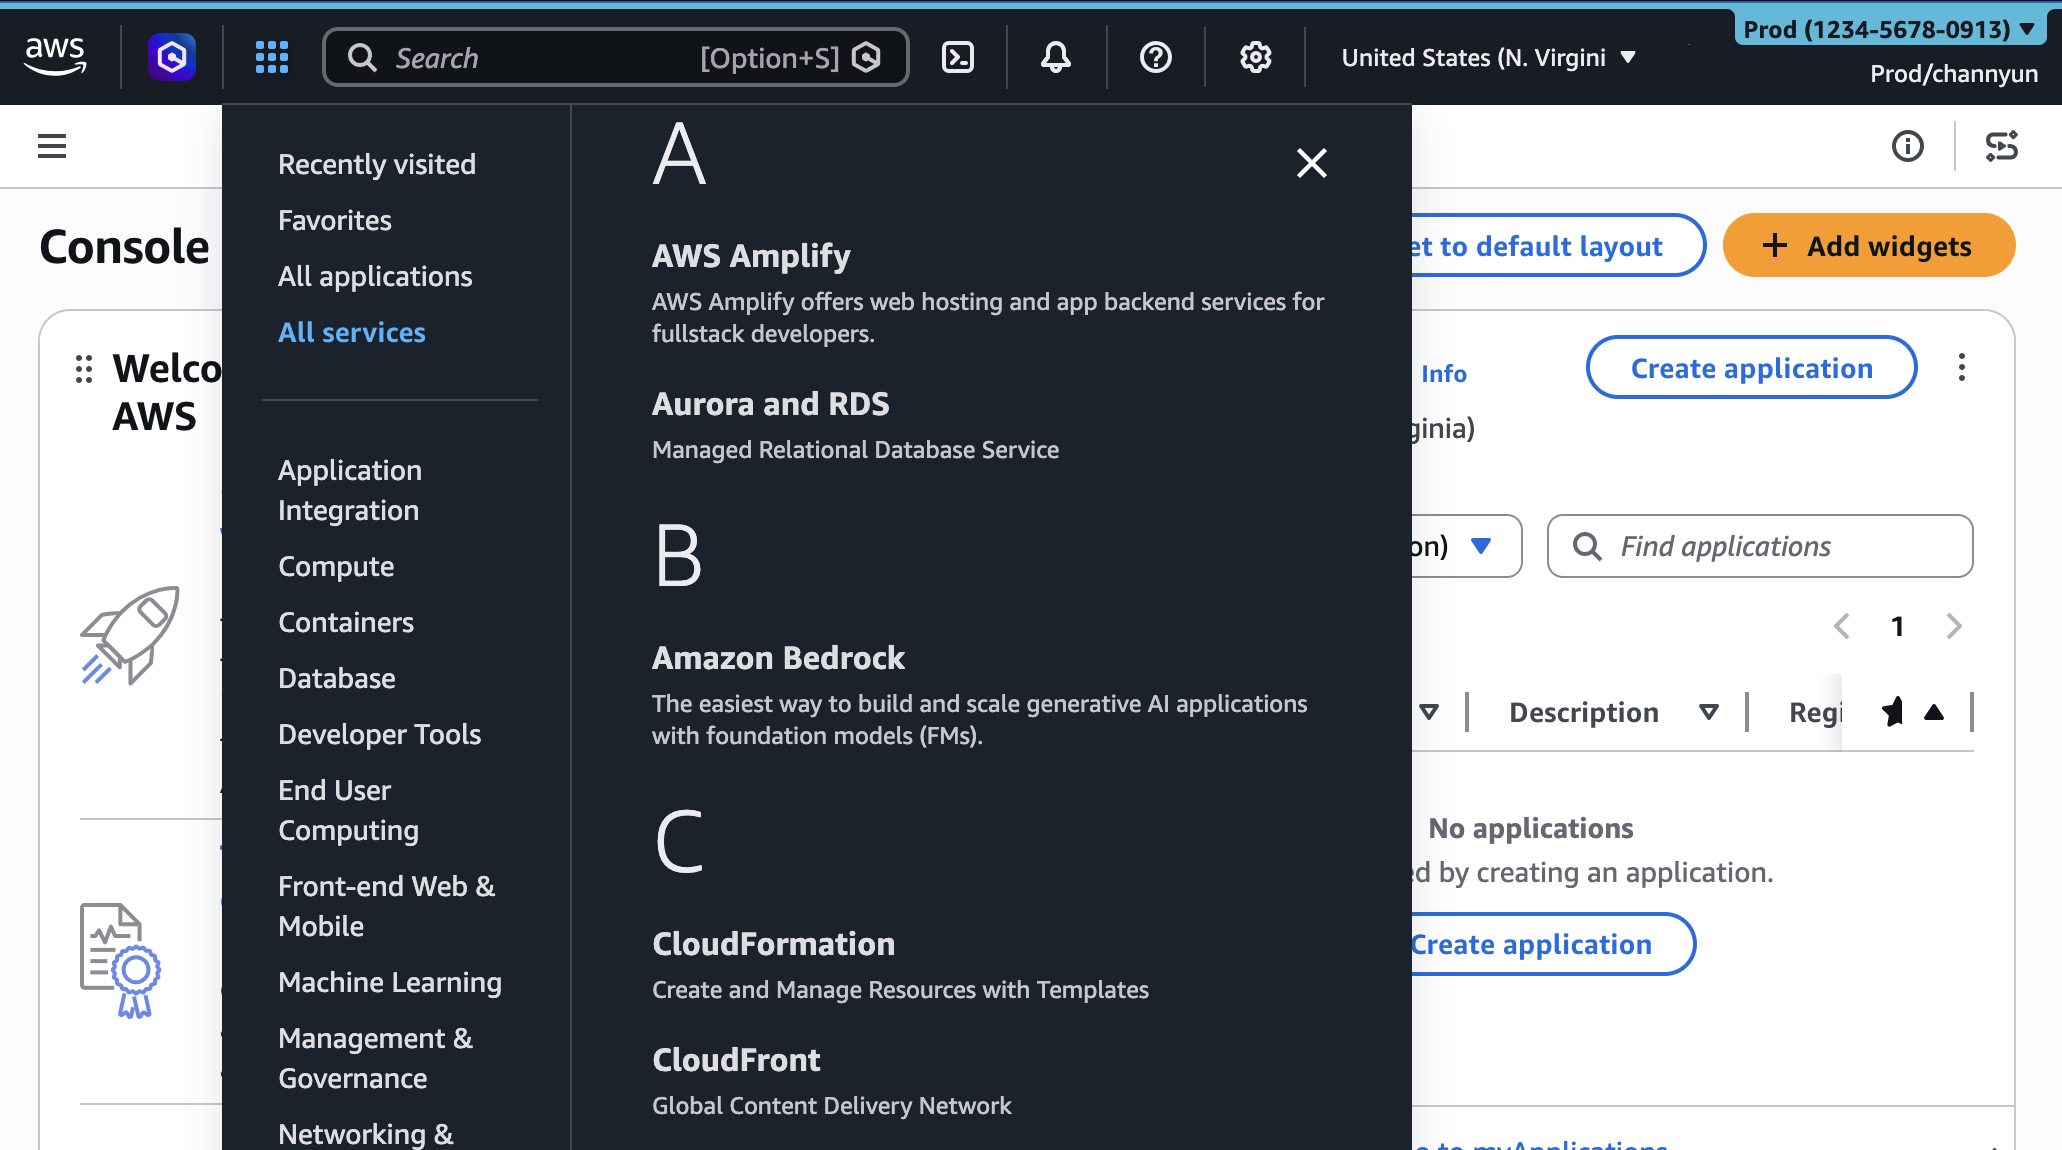
After configuring visible services setting, you will find only selected services in the All services menu on the navigation bar.

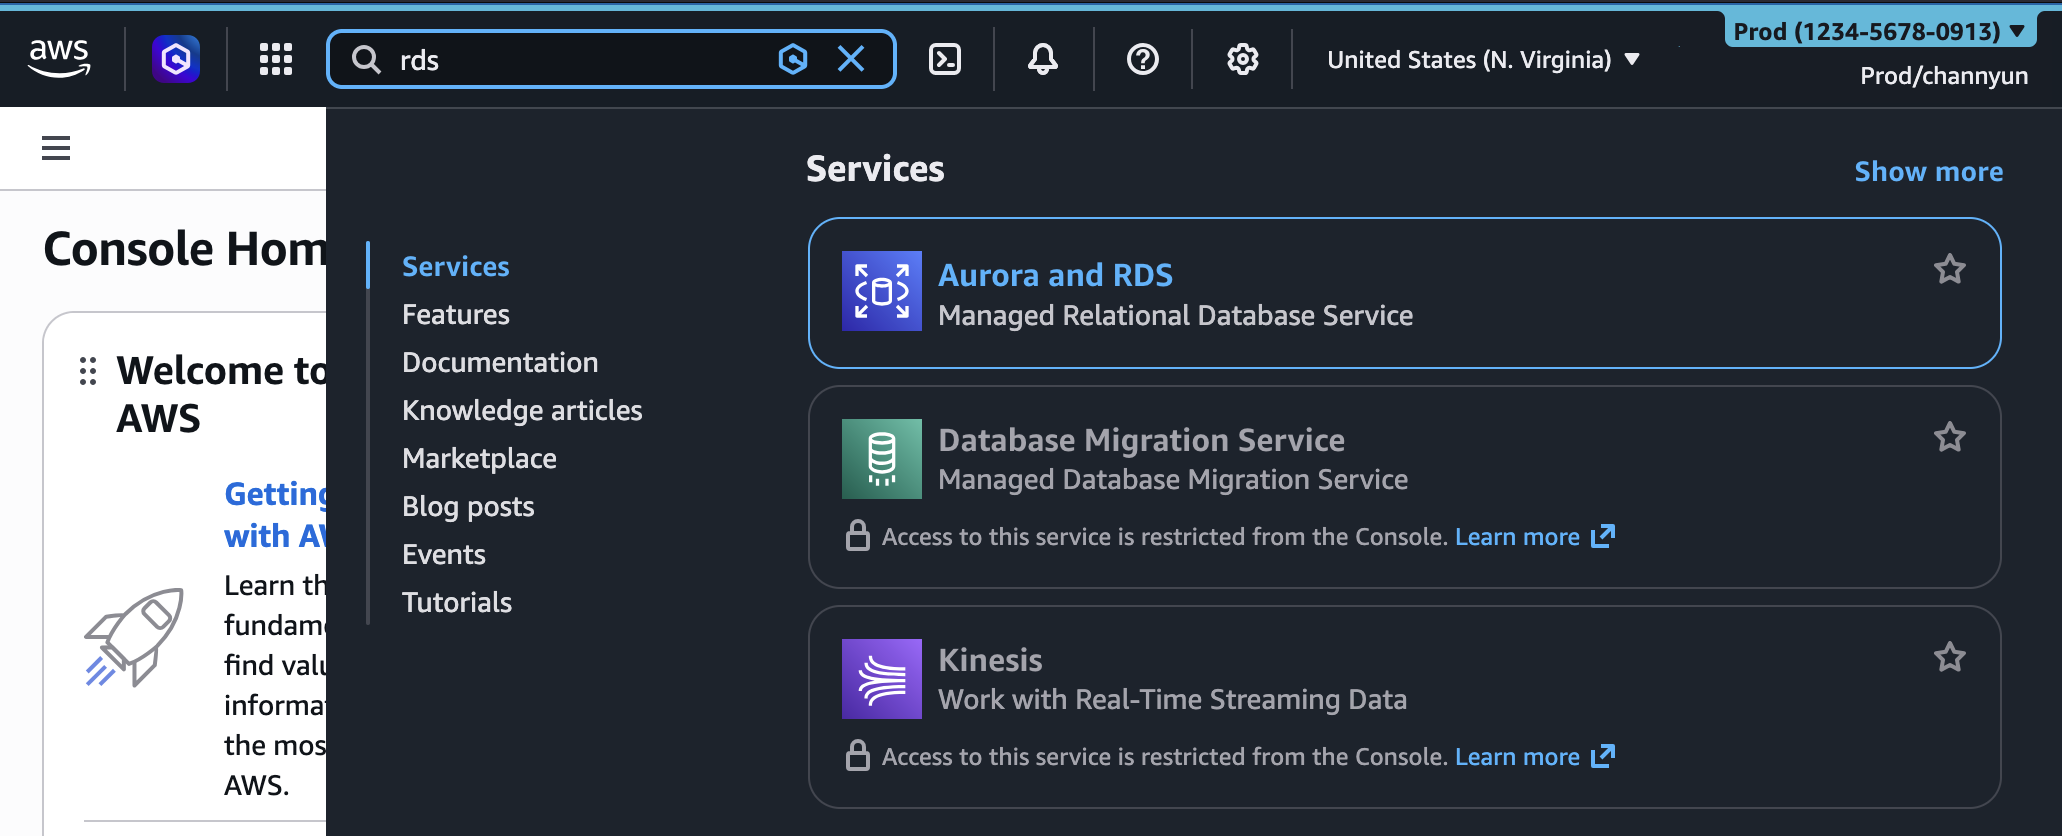
When you search the service name in the search bar, you can only choose selected services.

The Regions and services visibility settings control only the appearance of services and Regions in the console. They don’t restrict access through the AWS Command Line Interface (AWS CLI), AWS SDKs, AWS APIs, or Amazon Q Developer.

You can also manage these account customization settings programmatically with new visibleServices and visibleRegions parameters. For example, you can use AWS CloudFormation sample template:

AWSTemplateFormatVersion: "2010-09-09"
Description: Customize AWS Console appearance for this account

Resources:
  AccountCustomization:
    Type: AWS::UXC::AccountCustomization
    Properties:
      AccountColor: red
      VisibleServices:
        - s3
        - ec2
        - lambda
      VisibleRegions:
        - us-east-1
        - us-west-2

And you can deploy your Cloudformation template.

$ aws cloudformation deploy \
  --template-file account-customization.yaml \
  --stack-name my-account-customization

To learn more, visit the AWS User Experience Customization API Reference and AWS CloudFormation template reference.

Give it a try in the AWS Management Console today and provide feedback by selecting the Feedback link at the bottom of the console, posting to the AWS re:Post forum for the AWS Management Console, or reaching out to your AWS Support contacts.

— Channy

Announcing Amazon Aurora PostgreSQL serverless database creation in seconds

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-amazon-aurora-postgresql-serverless-database-creation-in-seconds/

At re:Invent 2025, Colin Lazier, vice president of databases at AWS, emphasized the importance of building at the speed of an idea—enabling rapid progress from concept to running application. Customers can already create production-ready Amazon DynamoDB tables and Amazon Aurora DSQL databases in seconds. He previewed creating an Amazon Aurora serverless database with the same speed, and customers have since requested quick access and speed to this capability.

Today, we’re announcing the general availability of a new express configuration for Amazon Aurora PostgreSQL, a streamlined database creation experience with preconfigured defaults designed to help you get started in seconds.

With only two clicks, you can have an Aurora PostgreSQL serverless database ready to use in seconds. You have the flexibility to modify certain settings during and after database creation in the new configuration. For example, you can change the capacity range for the serverless instance at the time of create or add read replicas, modify parameter groups after the database is created. Aurora clusters with express configuration are created without an Amazon Virtual Private Cloud (Amazon VPC) network and include an internet access gateway for secure connections from your favorite development tools – no VPN, or AWS Direct Connect required. Express configuration also sets up AWS Identity and Access Management (IAM) authentication for your administrator user by default, enabling passwordless database authentication from the beginning without additional configuration.

After it’s created, you have access to features available for Aurora PostgreSQL serverless, such as deploying additional read replicas for high availability and automated failover capabilities. This launch also introduces a new internet access gateway routing layer for Aurora. Your new serverless instance comes enabled by default with this feature, which allows your applications to connect securely from anywhere in the world through the internet using the PostgreSQL wire protocol from a wide range of developer tools. This gateway is distributed across multiple Availability Zones, offering the same level of high availability as your Aurora cluster.

Creating and connecting to Aurora in seconds means fundamentally rethinking how you get started. We launched multiple capabilities that work together to help you onboard and run your application with Aurora. Aurora is now available on AWS Free Tier, which you gain hands-on experience with Aurora at no upfront cost. After it’s created, you can directly query an Aurora database in AWS CloudShell or using programming languages and developer tools through a new internet accessible routing component for Aurora. With integrations such as v0 by Vercel, you can use natural language to start building your application with the features and benefits of Aurora.

Create an Aurora PostgreSQL serverless database in seconds
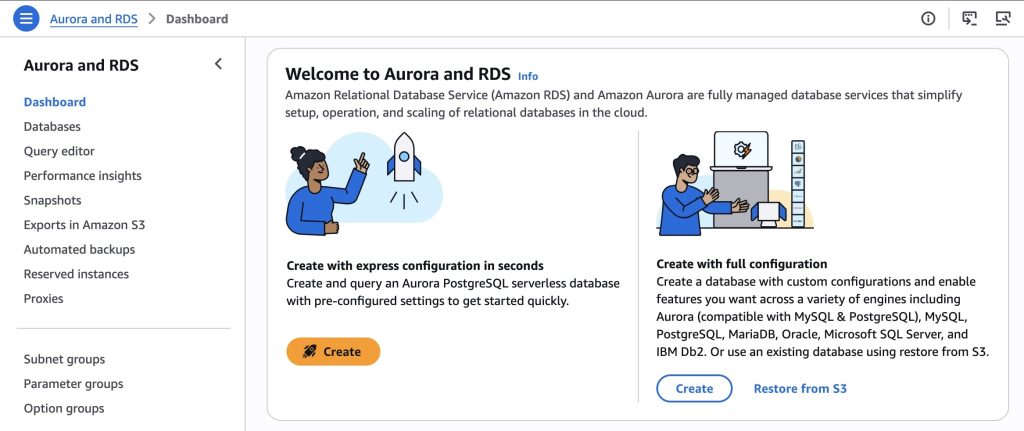
To get started, go to the Aurora and RDS console and in the navigation pane, choose Dashboard. Then, choose Create with a rocket icon.

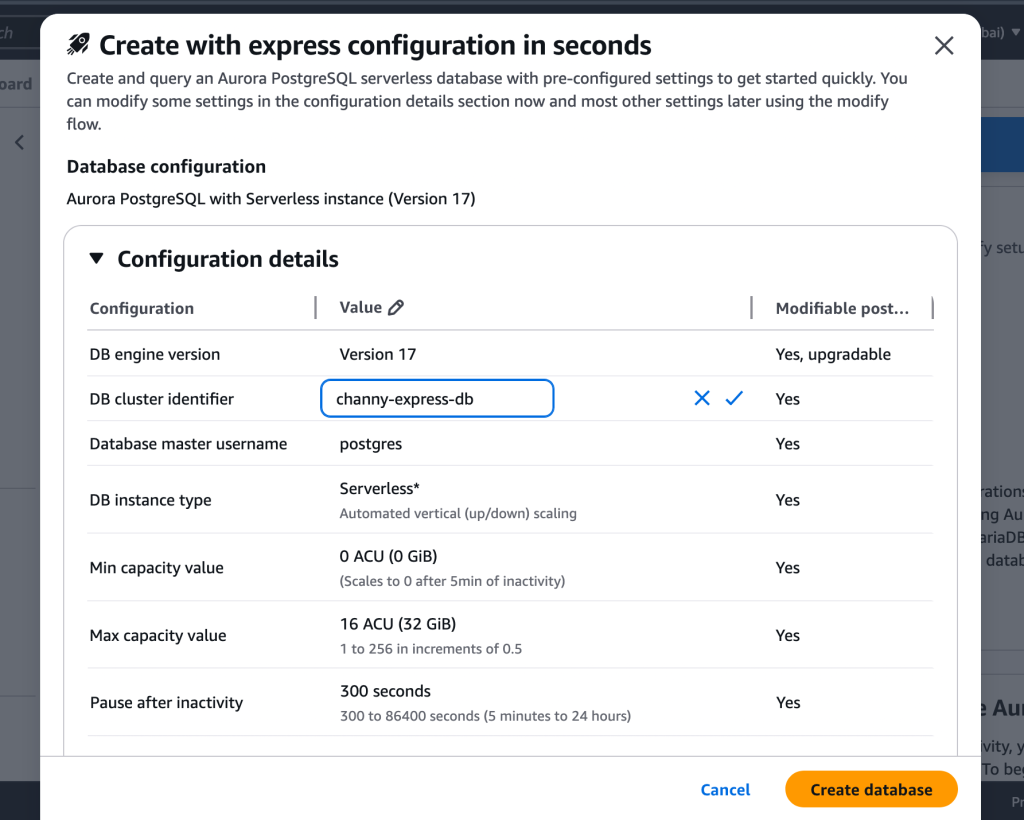
Review pre-configured settings in the Create with express configuration dialog box. You can modify the DB cluster identifier or the capacity range as needed. Choose Create database.

You can also use the AWS Command Line Interface (AWS CLI) or AWS SDKs with the parameter --express-configuration to create both a cluster and an instance within the cluster with a single API call which makes it ready for running queries in seconds.To learn more, visit Creating an Aurora PostgreSQL DB cluster with express configuration.

Here is a CLI command to create the cluster:

$ aws rds create-db-cluster --db-cluster-identifier channy-express-db \
    --engine aurora-postgresql \
    –with-express-configuration

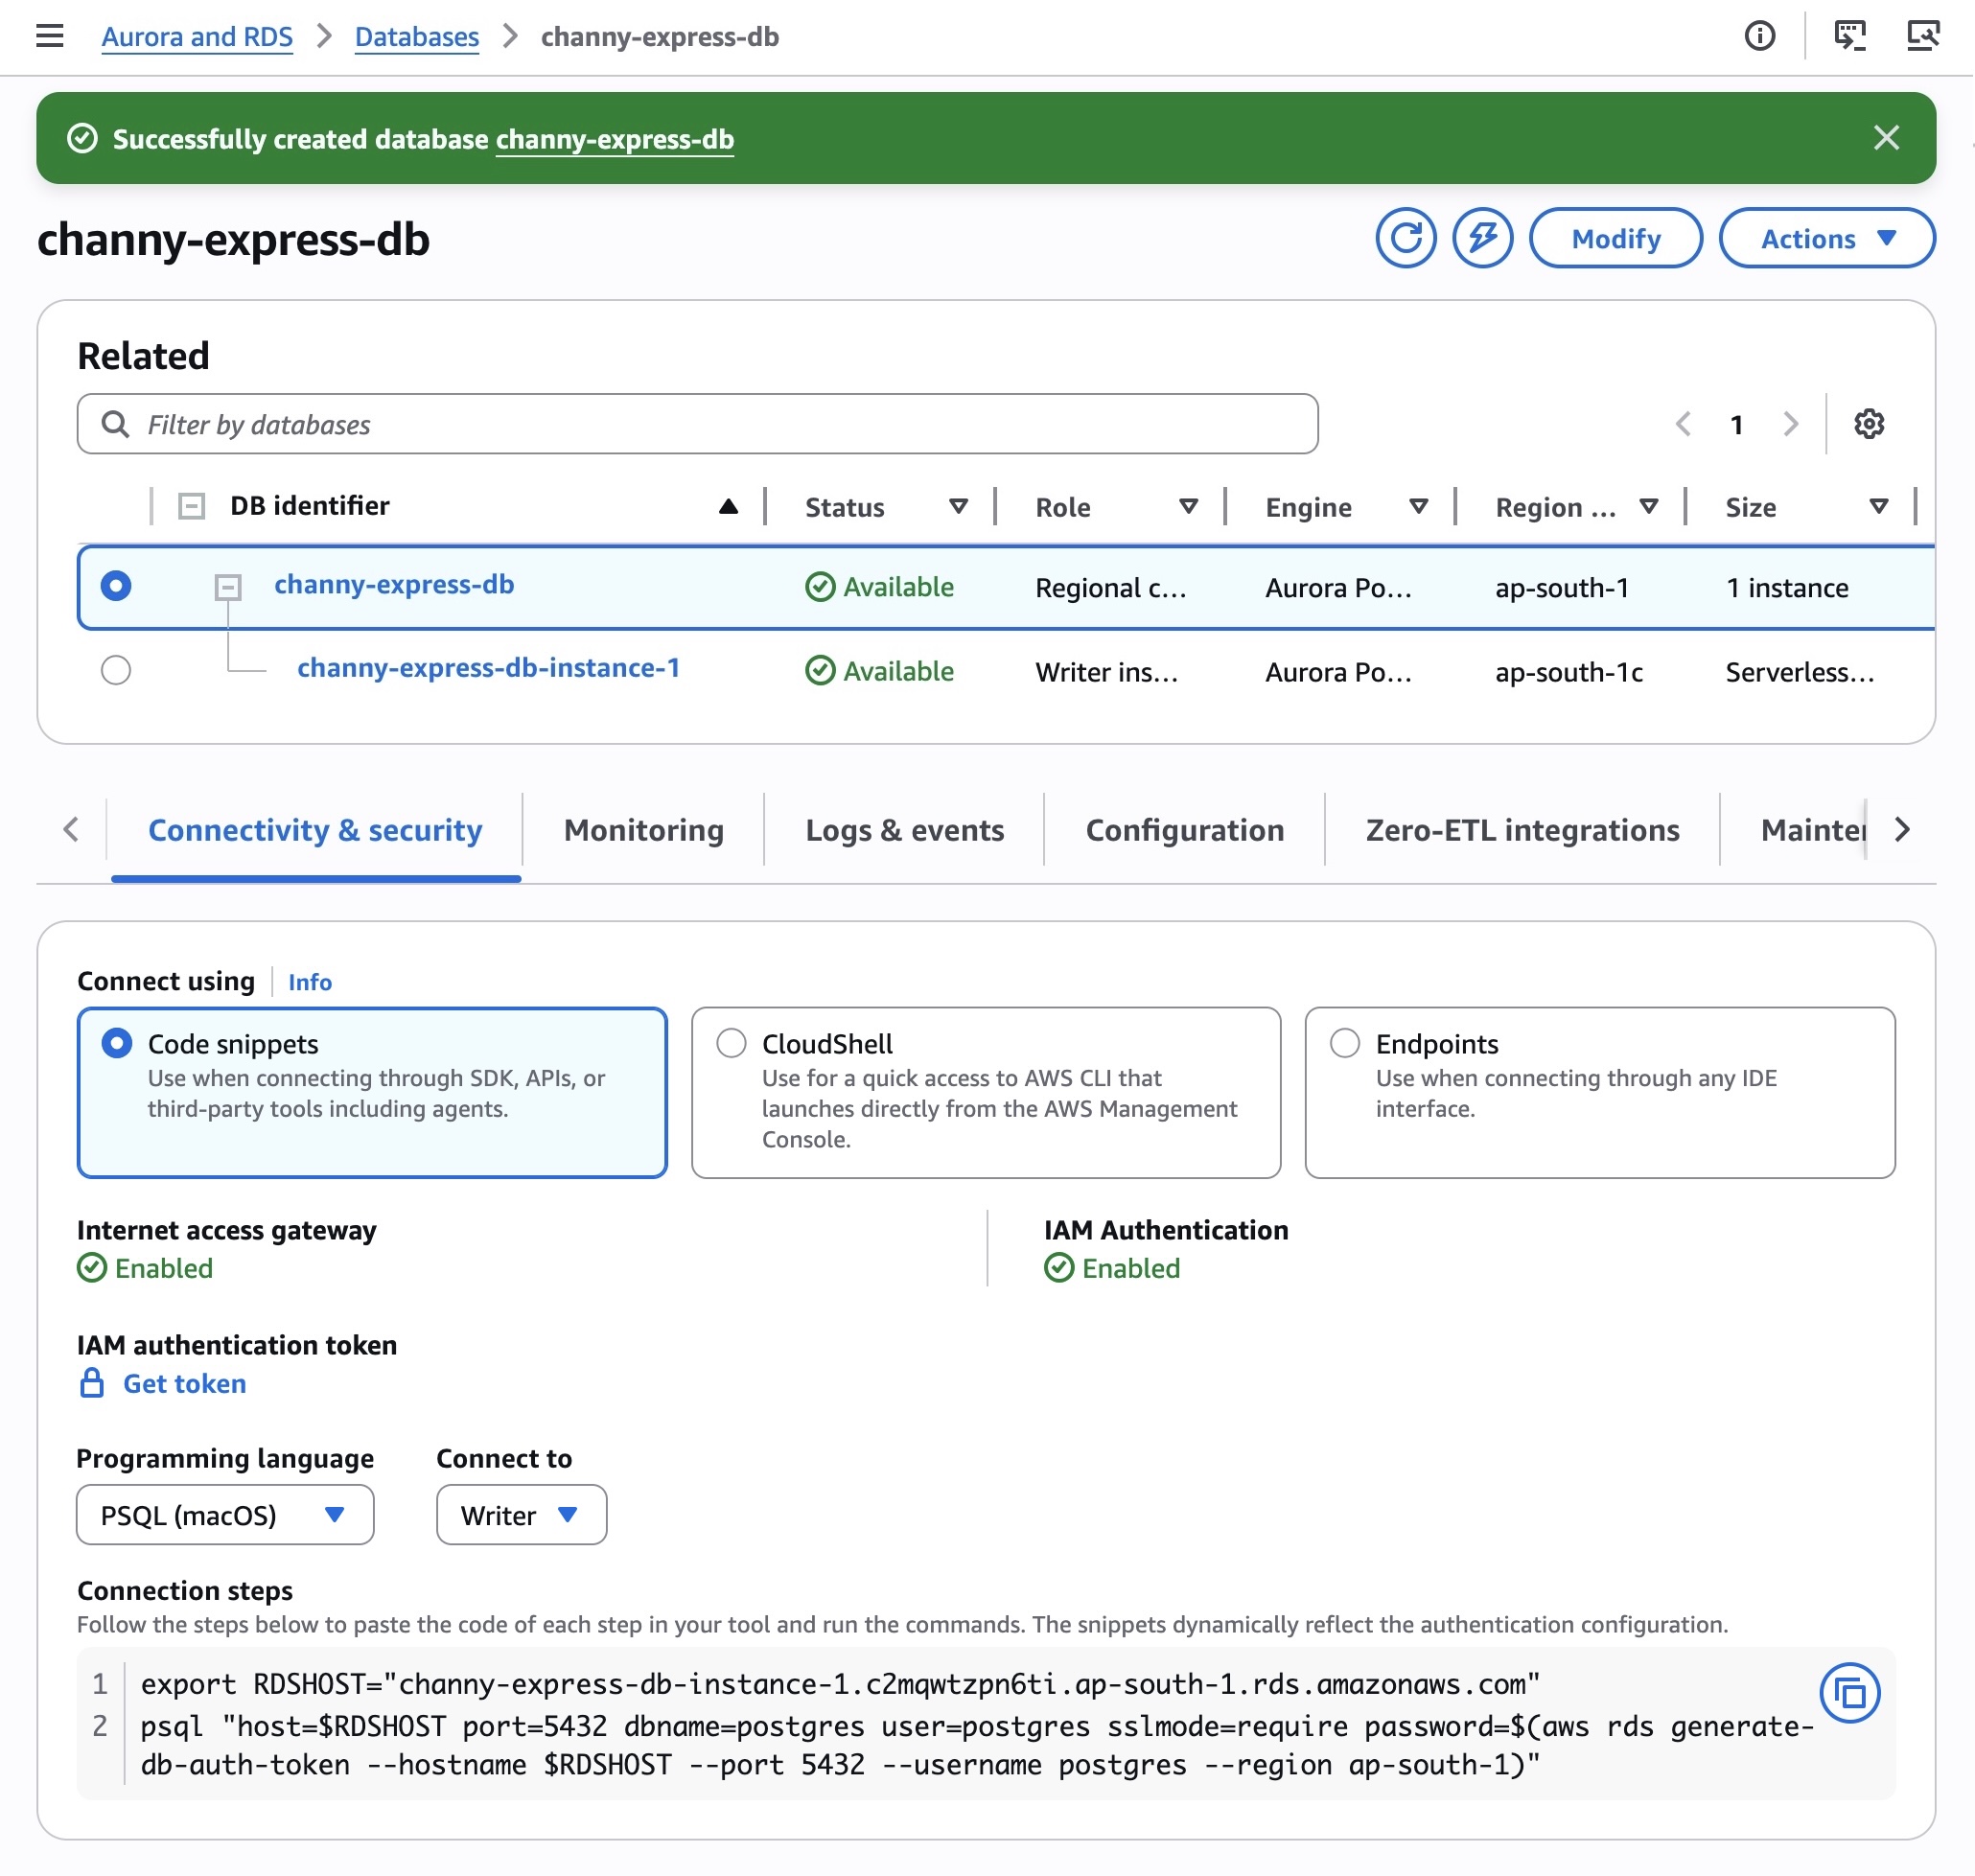
Your Aurora PostgreSQL serverless database should be ready in seconds. A success banner confirms the creation, and the database status changes to Available.

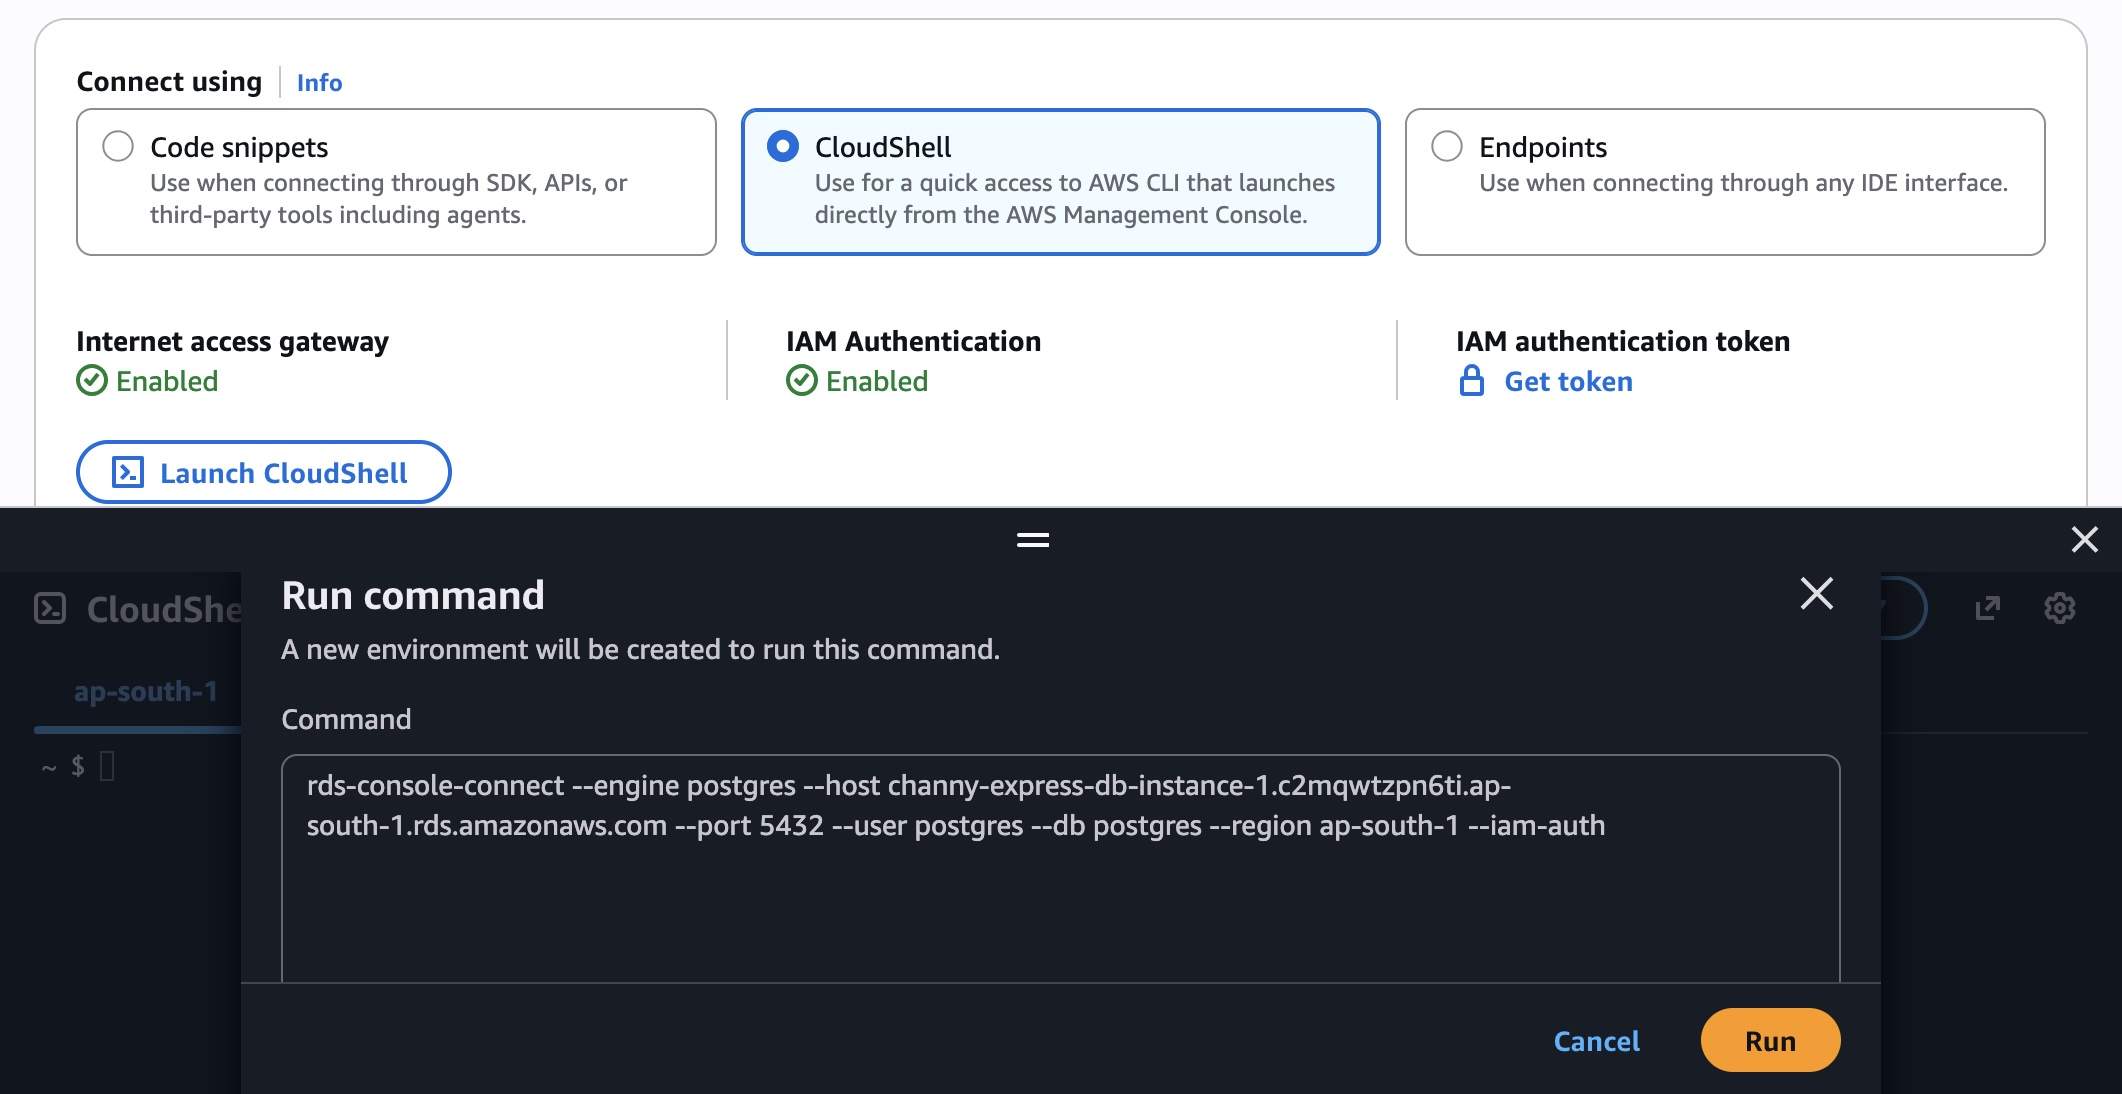
After your database is ready, go to the Connectivity & security tab to access three connection options. When connecting through SDKs, APIs, or third-party tools including agents, choose Code snippets. You can choose various programming languages such as .NET, Golang, JDBC, Node.js, PHP, PSQL, Python, and TypeScript. You can paste the code from each step into your tool and run the commands.

For example, the following Python code is dynamically generated to reflect the authentication configuration:

import psycopg2
import boto3

auth_token = boto3.client('rds', region_name='ap-south-1').generate_db_auth_token(DBHostname='channy-express-db-instance-1.abcdef.ap-south-1.rds.amazonaws.com', Port=5432, DBUsername='postgres', Region='ap-south-1')

conn = None
try:
    conn = psycopg2.connect(
        host='channy-express-db-instance-1.abcdef.ap-south-1.rds.amazonaws.com',
        port=5432,
        database='postgres',
        user='postgres',
        password=auth_token,
        sslmode='require'
    )
    cur = conn.cursor()
    cur.execute('SELECT version();')
    print(cur.fetchone()[0])
    cur.close()
except Exception as e:
    print(f"Database error: {e}")
    raise
finally:
    if conn:
        conn.close()

const { Client } = require('pg');
const AWS = require('aws-sdk');
AWS.config.update({ region: 'ap-south-1' });

async function main() {
  let password = '';
  const signer = new AWS.RDS.Signer({ region: 'ap-south-1', hostname: 'channy-express-db-instance-1.abcdef.ap-south-1.rds.amazonaws.com', port: 5432, username: 'postgres' });
  password = signer.getAuthToken({});

  const client = new Client({
    host: 'channy-express-db-instance-1.abcdef.ap-south-1.rds.amazonaws.com',
    port: 5432,
    database: 'postgres',
    user: 'postgres',
    password,
    ssl: { rejectUnauthorized: false }
  });

  try {
    await client.connect();
    const res = await client.query('SELECT version()');
    console.log(res.rows[0].version);
  } catch (error) {
    console.error('Database error:', error);
    throw error;
  } finally {
    await client.end();
  }
}
main().catch(console.error);

Choose CloudShell for quick access to the AWS CLI which launches directly from the console. When you choose Launch CloudShell, you can see the command is pre-populated with relevant information to connect to your specific cluster. After connecting to the shell, you should see the psql login and the postgres => prompt to run SQL commands.

You can also choose Endpoints to use tools that only support username and password credentials, such as pgAdmin. When you choose Get token, you use an AWS Identity and Access Management (IAM) authentication token generated by the utility in the password field. The token is generated for the master username that you set up at the time of creating the database. The token is valid for 15 minutes at a time. If the tool you’re using terminates the connection, you will need to generate the token again.

Building your application faster with Aurora databases
At re:Invent 2025, we announced enhancements to the AWS Free Tier program, offering up to $200 in AWS credits that can be used across AWS services. You’ll receive $100 in AWS credits upon sign-up and can earn an additional $100 in credits by using services such as Amazon Relational Database Service (Amazon RDS), AWS Lambda, and Amazon Bedrock. In addition, Amazon Aurora is now available across a broad set of eligible Free Tier database services.

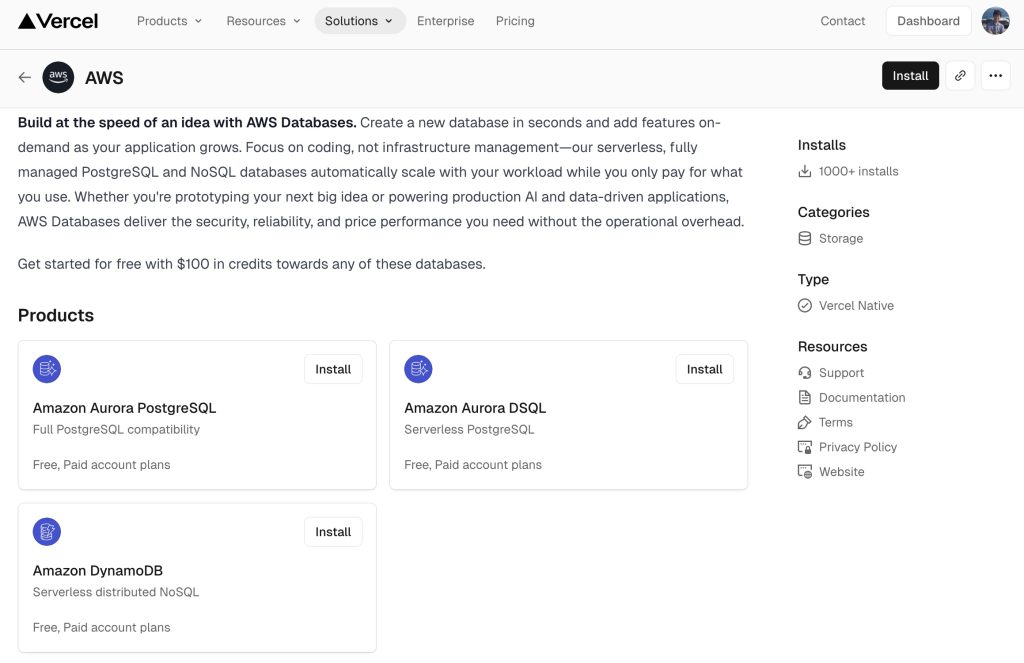
Developers are embracing platforms such as Vercel, where natural language is all it takes to build production-ready applications. We announced integrations with Vercel Marketplace to create and connect to an AWS database directly from Vercel in seconds and v0 by Vercel, an AI-powered tool that transforms your ideas into production-ready, full-stack web applications in minutes. It includes Aurora PostgreSQL, Aurora DSQL, and DynamoDB databases. You can also connect your existing databases created through express configuration with Vercel. To learn more, visit AWS for Vercel.

Like Vercel, we’re bringing our databases seamlessly into their experiences and are integrating directly with widely adopted frameworks, AI assistant coding tools, environments, and developer tools, all to unlock your ability to build at the speed of an idea.

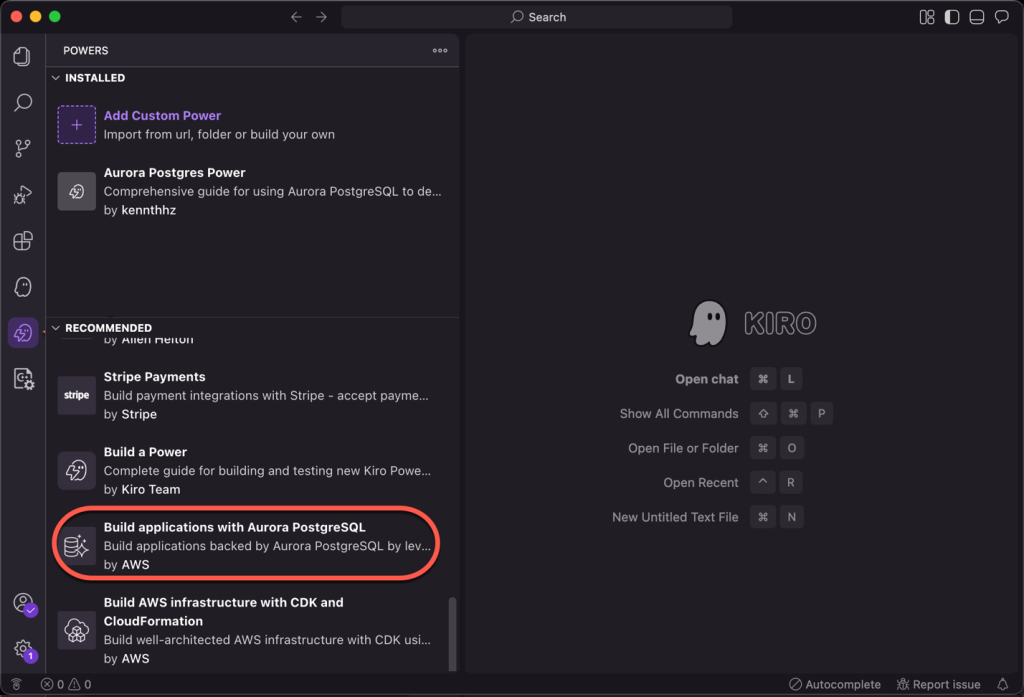
We introduced Aurora PostgreSQL integration with Kiro powers, which developers can use to build Aurora PostgreSQL backed applications faster with AI agent-assisted development through Kiro. You can use Kiro power for Aurora PostgreSQL within Kiro IDE and from the Kiro powers webpage for one-click installation. To learn more about this Kiro Power, read Introducing Amazon Aurora powers for Kiro and Amazon Aurora Postgres MCP Server.

Now available
You can create an Aurora PostgreSQL serverless database in seconds today in all AWS commercial Regions. For Regional availability and a future roadmap, visit the AWS Capabilities by Region.

You pay only for capacity consumed based on Aurora Capacity Units (ACUs) billed per second from zero capacity, which automatically starts up, shuts down, and scales capacity up or down based on your application’s needs. To learn more, visit the Amazon Aurora Pricing page.

Give it a try in the Aurora and RDS console and send feedback to AWS re:Post for Aurora PostgreSQL or through your usual AWS Support contacts.

— Channy

Our First 2026 Heroes Cohort Is Here!

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/our-first-2026-heroes-cohort-is-here/

We’re thrilled to celebrate three exceptional developer community leaders as AWS Heroes. These individuals represent the heart of what makes the AWS community so vibrant. In addition to sharing technical knowledge, they build connections, forge genuine human relationships, and create pathways for others to grow. From pioneering cloud culture in mountain villages to leading cybersecurity education across continents, these Heroes demonstrate that true leadership extends beyond technical expertise to the communities we build and the lives we impact.

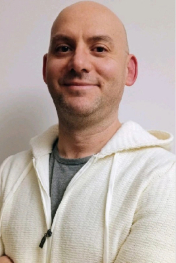
Maurizio – Pignola, Italy

Community Hero Maurizio is a CTO and organizer of the AWS User Group Basilicata, recognized for his dedication to building tech ecosystems where they previously did not exist. For over a decade, he has pioneered cloud culture through a philosophy centered on genuine human connection and knowledge transfer. He founded an international tech conference in a small mountain village, creating a unique space where global experts and local talent meet, blending deep technical sessions on cloud architectures, DevOps, and web scaling with unconventional networking experiences. Beyond organizing events, Maurizio is a tireless mentor working across generations, which span from introducing children to coding to helping university students and professionals transition into cloud architecture. His impact is defined by a rare combination of technical leadership and inclusive community building that draws people from across Europe.

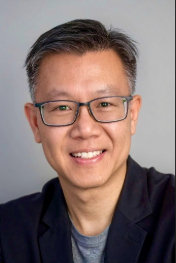
Ray Goh – Singapore

Artificial Intelligence Hero Ray Goh is a seasoned AWS machine learning and AI community leader based in Singapore and a long-standing contributor in various AWS community programs since 2018, from AWS ASEAN Cloud Warrior and AWS Dev/Cloud Alliance to being part of the pioneer batch of AWS Community Builders in 2020. He founded The Gen-C (a Generative AI Learning Community) in 2024, organizing regular public workshops at libraries across Singapore on topics ranging from LLM fine-tuning to AI agents on AWS. Ray has spoken at AWS re:Invent, AWS Summit ASEAN, AWS Community Day Hong Kong, and numerous user group meetups, and guest-authored for the AWS Machine Learning Blog. He spearheaded the world’s largest enterprise AWS DeepRacer program for DBS Bank in 2020, upskilling over 3,100 employees, and trained more than 1,300 ASEAN students in LLM techniques in 2025. His community work extends to skills-based CSR initiatives teaching AI and machine learning to women, children, and youths, with contributions featured on CNBC and Euromoney.

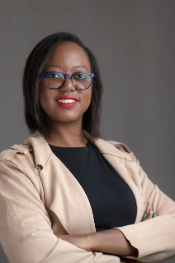
Sheyla Leacock – Panama City, Panama

Security Hero Sheyla Leacock is an IT security professional, mentor, technical author, and international speaker contributing to the global cloud and cybersecurity community. She has spoken at AWS Summit Mexico, AWS Summit LATAM in Peru, and led PeerTalk sessions at AWS re:Invent, while also leading the AWS User Group in Panama and regularly participating in AWS Community Days and regional meetups. Beyond AWS-focused events, she has delivered talks at more than 20 international conferences and publishes technical articles and educational content on AWS cloud computing and cybersecurity. She collaborates with universities as a guest lecturer, supporting the development of emerging technology and cybersecurity talent. Through community leadership, knowledge sharing, and education, she contributes to strengthening the AWS and cybersecurity ecosystem.

Learn More

Visit the AWS Heroes webpage if you’d like to learn more about the AWS Heroes program, or to connect with a Hero near you.

— Taylor

Introducing account regional namespaces for Amazon S3 general purpose buckets

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-account-regional-namespaces-for-amazon-s3-general-purpose-buckets/

Today, we’re announcing a new feature of Amazon Simple Storage Service (Amazon S3) you can use to create general purpose buckets in your own account regional namespace simplifying bucket creation and management as your data storage needs grow in size and scope. You can create general purpose bucket names across multiple AWS Regions with assurance that your desired bucket names will always be available for you to use.

With this feature, you can predictably name and create general purpose buckets in your own account regional namespace by appending your account’s unique suffix in your requested bucket name. For example, I can create the bucket mybucket-123456789012-us-east-1-an in my account regional namespace. mybucket is the bucket name prefix that I specified, then I add my account regional suffix to the requested bucket name: -123456789012-us-east-1-an. If another account tries to create buckets using my account’s suffix, their requests will be automatically rejected.

Your security teams can use AWS Identity and Access Management (AWS IAM) policies and AWS Organizations service control policies to enforce that your employees only create buckets in their account regional namespace using the new s3:x-amz-bucket-namespace condition key, helping teams adopt the account regional namespace across your organization.

Create your S3 bucket with account regional namespace in action
To get started, choose Create bucket in the Amazon S3 console. To create your bucket in your account regional namespace, choose Account regional namespace. If you choose this option, you can create your bucket with any name that is unique to your account and region.

This configuration supports all of the same features as general purpose buckets in the global namespace. The only difference is that only your account can use bucket names with your account’s suffix. The bucket name prefix and the account regional suffix combined must be between 3 and 63 characters long.

Using the AWS Command Line Interface (AWS CLI), you can create a bucket with account regional namespace by specifying the x-amz-bucket-namespace:account-regional request header and providing a compatible bucket name.

$ aws s3api create-bucket --bucket mybucket-123456789012-us-east-1-an \
   --bucket-namespace account-regional \
   --region us-east-1

You can use the AWS SDK for Python (Boto3) to create a bucket with account regional namespace using CreateBucket API request.

import boto3

class AccountRegionalBucketCreator:
    """Creates S3 buckets using account-regional namespace feature."""
    
    ACCOUNT_REGIONAL_SUFFIX = "-an"
    
    def __init__(self, s3_client, sts_client):
        self.s3_client = s3_client
        self.sts_client = sts_client
    
    def create_account_regional_bucket(self, prefix):
        """
        Creates an account-regional S3 bucket with the specified prefix.
        Resolves caller AWS account ID using the STS GetCallerIdentity API.
        Format: ---an
        """
        account_id = self.sts_client.get_caller_identity()['Account']
        region = self.s3_client.meta.region_name
        bucket_name = self._generate_account_regional_bucket_name(
            prefix, account_id, region
        )
        
        params = {
            "Bucket": bucket_name,
            "BucketNamespace": "account-regional"
        }
        if region != "us-east-1":
            params["CreateBucketConfiguration"] = {
                "LocationConstraint": region
            }
        
        return self.s3_client.create_bucket(**params)
    
    def _generate_account_regional_bucket_name(self, prefix, account_id, region):
        return f"{prefix}-{account_id}-{region}{self.ACCOUNT_REGIONAL_SUFFIX}"


if __name__ == '__main__':
    s3_client = boto3.client('s3')
    sts_client = boto3.client('sts')
    
    creator = AccountRegionalBucketCreator(s3_client, sts_client)
    response = creator.create_account_regional_bucket('test-python-sdk')
    
    print(f"Bucket created: {response}")

You can update your infrastructure as code (IaC) tools, such as AWS CloudFormation, to simplify creating buckets in your account regional namespace. AWS CloudFormation offers the pseudo parameters, AWS::AccountId and AWS::Region, making it easy to build CloudFormation templates that create account regional namespace buckets.

The following example demonstrates how you can update your existing CloudFormation templates to start creating buckets in your account regional namespace:

BucketName: !Sub "amzn-s3-demo-bucket-${AWS::AccountId}-${AWS::Region}-an"
BucketNamespace: "account-regional"

Alternatively, you can also use the BucketNamePrefix property to update your CloudFormation template. By using the BucketNamePrefix, you can provide only the customer defined portion of the bucket name and then it automatically adds the account regional namespace suffix based on the requesting AWS account and Region specified.

BucketNamePrefix: 'amzn-s3-demo-bucket'
BucketNamespace: "account-regional"

Using these options, you can build a custom CloudFormation template to easily create general purpose buckets in your account regional namespace.

Things to know
You can’t rename your existing global buckets to bucket names with account regional namespace, but you can create new general purpose buckets in your account regional namespace. Also, the account regional namespace is only supported for general purpose buckets. S3 table buckets and vector buckets already exist in an account-level namespace and S3 directory buckets exist in a zonal namespace.

To learn more, visit Namespaces for general purpose buckets in the Amazon S3 User Guide.

Now available
Creating general purpose buckets in your account regional namespace in Amazon S3 is now available in 37 AWS Regions including the AWS China and AWS GovCloud (US) Regions. You can create general purpose buckets in your account regional namespace at no additional cost.

Give it a try in the Amazon S3 console today and send feedback to AWS re:Post for Amazon S3 or through your usual AWS Support contacts.

— Channy

Introducing OpenClaw on Amazon Lightsail to run your autonomous private AI agents

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-openclaw-on-amazon-lightsail-to-run-your-autonomous-private-ai-agents/

Today, we’re announcing the general availability of OpenClaw on Amazon Lightsail to launch OpenClaw instance, pairing your browser, enabling AI capabilities, and optionally connecting messaging channels. Your Lightsail OpenClaw instance is pre-configured with Amazon Bedrock as the default AI model provider. Once you complete setup, you can start chatting with your AI assistant immediately — no additional configuration required.

OpenClaw is an open-source self-hosted autonomous private AI agent that acts as a personal digital assistant by running directly on your computer. You can AI agents on OpenClaw through your browser to connect to messaging apps like WhatsApp, Discord, or Telegram to perform tasks such as managing emails, browsing the web, and organizing files, rather than just answering questions.

AWS customers have asked if they can run OpenClaw on AWS. Some of them blogged about running OpenClaw on Amazon EC2 instances. As someone who has experienced installing OpenClaw directly on my home device, I learned that this is not easy and that there are many security considerations.

So, let me introduce how to launch a pre-configured OpenClaw instance on Amazon Lightsail more easily and run it securely.

OpenClaw on Amazon Lightsail in action
To get started, go to the Amazon Lightsail console and choose Create instance on the Instances section. After choosing your preferred AWS Region and Availability Zone, Linux/Unix platform to run your instance, choose OpenClaw under Select a blueprint.

You can choose your instance plan (4 GB memory plan is recommended for optimal performance) and enter a name for your instance. Finally choose Create instance. Your instance will be in a Running state in a few minutes.

Before you can use the OpenClaw dashboard, you should pair your browser with OpenClaw. This creates a secure connection between your browser session and OpenClaw. To pair your browser with OpenClaw, choose Connect using SSH in the Getting started tab.

When a browser-based SSH terminal opens, you can see the dashboard URL, security credentials displayed in the welcome message. Copy them and open the dashboard in a new browser tab. In the OpenClaw dashboard, you can paste the copied access token into the Gateway Token field in the OpenClaw dashboard.

When prompted, press y to continue and a to approve with device pairing in the SSH terminal. When pairing is complete, you can see the OK status in the OpenClaw dashboard and your browser is now connected to your OpenClaw instance.

Your OpenClaw instance on Lightsail is configured to use Amazon Bedrock to power its AI assistant. To enable Bedrock API access, copy the script in the Getting started tab and run copied script into the AWS CloudShell terminal.

Once the script is complete, go to Chat in the OpenClaw dashboard to start using your AI assistant!

You can set up OpenClaw to work with messaging apps like Telegram and WhatsApp for interacting with your AI assistant directly from your phone or messaging client. To learn more, visit Get started with OpenClaw on Lightsail in the Amazon Lightsail User Guide.

Things to know
Here are key considerations to know about this feature:

  • Permission — You can customize AWS IAM permissions granted to your OpenClaw instance. The setup script creates an IAM role with a policy that grants access to Amazon Bedrock. You can customize this policy at any time. But, you should be careful when modifying permissions because it may prevent OpenClaw from generating AI responses. To learn more, visit AWS IAM policies in the AWS documentation
  • Cost — You pay for the instance plan you selected on an on-demand hourly rate only for what you use. Every message sent to and received from the OpenClaw assistant is processed through Amazon Bedrock using a token-based pricing model. If you select a third-party model distributed through AWS Marketplace such as Anthropic Claude or Cohere, there may be additional software fees on top of the per-token cost.
  • Security — Running a personal AI agent on OpenClaw is powerful, but it may cause security threat if you are careless. I recommend to hide your OpenClaw gateway never to expose it to open internet. The gateway auth token is your password, so rotate it often and store it in your envirnment file not hardcoded in config file. To learn more about security tips, visit Security on OpenClaw gateway.

Now available
OpenClaw on Amazon Lightsail is now available in all AWS commercial Regions where Amazon Lightsail is available. For Regional availability and a future roadmap, visit the AWS Capabilities by Region.

Give a try in the Lightsail console and send feedback to AWS re:Post for Amazon Lightsail or through your usual AWS support contacts.

– Channy

AWS Security Hub Extended offers full-stack enterprise security with curated partner solutions

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-security-hub-extended-offers-full-stack-enterprise-security-with-curated-partner-solutions/

At re:Invent 2025, we introduced a completely re-imagined AWS Security Hub that unifies AWS security services, including Amazon GuardDuty and Amazon Inspector into a single experience. This unified experience automatically and continuously analyzes security findings in combination to help you prioritize and respond to your critical security risks.

Today, we’re announcing AWS Security Hub Extended, a plan of Security Hub that simplifies how you procure, deploy, and integrate a full-stack enterprise security solution across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. With the Extended plan, you can expand your security portfolio beyond AWS to help protect your enterprise estate through a curated selection of AWS Partner solutions, including 7AI, Britive, CrowdStrike, Cyera, Island, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, Splunk, a Cisco company, Upwind, and Zscaler.

With AWS as the seller of record, you benefit from pre-negotiated pay-as-you-go pricing, a single bill, and no long-term commitments. You can also get unified security operations experience within Security Hub and unified Level 1 support for AWS Enterprise Support customers. You told us that managing multiple procurement cycles and vendor negotiations was creating unnecessary complexity, costing you time and resources. In response, we’ve curated these partner offerings for you to establish more comprehensive protection across your entire technology stack through a single, simplified experience.

Security findings from all participating solutions are emitted in the Open Cybersecurity Schema Framework (OCSF) schema and automatically aggregated in AWS Security Hub. With the Extended plan, you can combine AWS and partner security solutions to quickly identify and respond to risks that span boundaries.

The Security Hub Extended plan in action
You can access the partner solutions directly within the Security Hub console by selecting Extended plan under the Management menu. From there, you can review and deploy any combination of curated and partner offerings.

You can review details of each partner offering directly in the Security Hub console and subscribe. When you subscribe, you’ll be directed to an automated on-boarding experience from each partner. Once onboarded, consumption-based metering is automatic and you are billed monthly as part of your Security Hub bill.

Security findings from all solutions are automatically consolidated in AWS Security Hub. This gives you immediate and direct access to all security findings in normalized OCSF schema.

To learn more about how to enhance your security posture with these integrations for AWS Security Hub, visit the AWS Security Hub User Guide.

Now available
The AWS Security Hub Extended plan is now generally available in all AWS commercial Regions where Security Hub is available. You can use flexible pay-as-you-go or flat-rate pricing—no upfront investments or long-term commitments required. For more information about pricing, visit the AWS Security Hub pricing page.

Give it a try today in the Security Hub console and send feedback to AWS re:Post for Security Hub or through your usual AWS Support contacts.

— Channy

Transform live video for mobile audiences with AWS Elemental Inference

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/transform-live-video-for-mobile-audiences-with-aws-elemental-inference/

Today, we’re announcing AWS Elemental Inference, a fully managed AI service that automatically transforms and maximizes live and on-demand video broadcasts to engage audiences at scale. At launch, you’ll be able to use AWS Elemental Inference to adapt video content into vertical formats optimized for mobile and social platforms in real time.

With AWS Elemental Inference, broadcasters and streamers can reach audiences on social and mobile platforms such as TikTok, Instagram Reels, and YouTube Shorts without manual postproduction work or AI expertise.

Today’s viewers consume content differently than they did even a few years ago. However, most broadcasts are produced in landscape format for traditional viewing. Converting these broadcasts into vertical formats for mobile platforms typically requires time-consuming manual editing that causes broadcasters and streamers to miss viral moments and lose audiences to mobile-first destinations.

Let’s try it out
AWS Elemental Inference offers flexible deployment options to fit your existing workflow. You can choose to create a feed through the standalone console or configure AWS Elemental Inference through the AWS Elemental MediaLive console.

AWS Elemental Inference console

To get started with AWS Elemental Inference, navigate to the AWS Management Console and choose AWS Elemental Inference. From the dashboard, choose Create feed to establish your top-level resource for AI-powered video processing. A feed contains your feature configurations and begins in CREATING state before transitioning to AVAILABLE when ready.

AWS Elemental Inference console

After creating your feed, you can configure outputs for either vertical video cropping or clip generation. For cropping, you can start with an empty feed. The service automatically manages cropping parameters based on your video specifications. For clip generation, choose Add output, provide a name (such as “highlight-clips”), select Clipping as the output type, and set the status to ENABLED.

This standalone interface provides a streamlined experience for configuring and managing your AI-powered video transformations, making it straightforward to get started with vertical video creation and clip generation.

AWS MediaLive inference

Alternatively, you can enable AWS Elemental Inference directly within your AWS Elemental MediaLive channel configuration. You can use this integrated approach to add AI capabilities to your existing live video workflows without modifying your architecture. Enable the features you need as part of your channel setup, and AWS Elemental Inference will work in parallel with your video encoding.

AWS MediaLive inference console

After it’s enabled, you can configure Smart Crop with outputs for different resolution specifications within an Output group.

AWS MediaLive inference console

AWS Elemental MediaLive now includes a dedicated AWS Elemental Inference tab on the channel details page, providing a centralized view of your AI-powered video transformation configuration. The tab displays the service Amazon Resource Name (ARN), data endpoints, and feed output details, including which features, such as Smart Crop, are enabled and their current operational status.

How AWS Elemental Inference works
The service uses an agentic AI application that analyses video in real time and automatically applies the right optimizations at the right moments. Detection of vertical video cropping and clip generation happens independently, executing multistep transformations that require no human intervention to extract value.

AWS Elemental Inference analyzes video and automatically applies AI capabilities with no human-in-the-loop prompting required. While you focus on quality video production, the service autonomously optimizes content to create personalized content experiences for your audience.

AWS Elemental Inference applies AI capabilities in parallel with live video, achieving 6–10 second latency compared to minutes for traditional postprocessing approaches. This “process once, optimize everywhere” method runs multiple AI features simultaneously on the same video stream, eliminating the need to reprocess content for each capability.

The service integrates seamlessly with AWS Elemental MediaLive, so you can enable AI features without modifying your existing video architecture. AWS Elemental Inference uses fully managed foundation models (FMs) that are automatically updated and optimized, so you don’t need dedicated AI teams or specialized expertise.

Key features at launch
Enjoy the following key features when AWS Elemental Inference launches:

  • Vertical video creation – AI-powered cropping intelligently transforms landscape broadcasts into vertical formats (9:16 aspect ratio) optimized for social and mobile platforms. The service tracks subjects and keeps key action visible, maintaining broadcast quality while automatically reformatting content for mobile viewing.
  • Clip generation with advanced metadata analysis – Automatically detects and extracts clips from live content, highlighting moments for real-time distribution. For live broadcasts, this means identifying game-winning plays in soccer and basketball—reducing manual editing from hours to minutes.

Keep an eye on this space as more features and capabilities will be introduced throughout this year, including tighter integration with core AWS Elemental services and features to help customers monetize their video content.

Now available
AWS Elemental Inference is available today in 4 AWS Regions: US East (N. Virginia), US West (Oregon), Europe (Ireland), and Asia Pacific (Mumbai). You can enable AWS Elemental Inference through the AWS Elemental MediaLive console or integrate it into your workflows using the AWS Elemental MediaLive APIs.

With consumption-based pricing, you pay only for the features you use and the video you process, with no upfront costs or commitments. This means you can scale during peak events and optimize costs during quieter periods.

To learn more about AWS Elemental Inference, visit the AWS Elemental Inference product page. For technical implementation details, see the AWS Elemental Inference documentation.


AWS Weekly Roundup: Claude Sonnet 4.6 in Amazon Bedrock, Kiro in GovCloud Regions, new Agent Plugins, and more (February 23, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-sonnet-4-6-in-amazon-bedrock-kiro-in-govcloud-regions-new-agent-plugins-and-more-february-23-2026/

Last week, my team met many developers at Developer Week in San Jose. My colleague, Vinicius Senger delivered a great keynote about renascent software—a new way of building and evolving applications where humans and AI collaborate as co-developers using Kiro. Other colleagues spoke about building and deploying production-ready AI agents. Everyone stayed to ask and hear the questions related to agent memory, multi-agent patterns, meta-tooling and hooks. It was interesting how many developers were actually building agents.

We are continuing to meet developers and hear their feedback at third-party developer conferences. You can meet us at the dev/nexus, the largest and longest-running Java ecosystem conference on March 4-6 in Atlanta. My colleague, James Ward will speak about building AI Agents with Spring and MCP, and Vinicius Senger and Jonathan Vogel will speak about 10 tools and tips to upgrade your Java code with AI. I’ll keep sharing places for you to connect with us.

Last week’s launches
Here are some of the other announcements from last week:

  • Claude Sonnet 4.6 model in Amazon Bedrock – You can now use Claude Sonnet 4.6 which offers frontier performance across coding, agents, and professional work at scale. Claude Sonnet 4.6 approaches Opus 4.6 intelligence at a lower cost. It enables faster, high-quality task completion, making it ideal for high-volume coding and knowledge work use cases.
  • Amazon EC2 Hpc8a instances powered by 5th Gen AMD EPYC processors – You can use new Hpc8a instances delivering up to 40% higher performance, increased memory bandwidth, and 300 Gbps Elastic Fabric Adapter networking. You can accelerate compute-intensive simulations, engineering workloads, and tightly coupled HPC applications.
  • Amazon SageMaker Inference for custom Amazon Nova models – You can now configure the instance types, auto-scaling policies, and concurrency settings for custom Nova model deployments with Amazon SageMaker Inference to best meet your needs.
  • Nested virtualization on virtual Amazon EC2 instances – You can create nested virtual machines by running KVM or Hyper-V on virtual EC2 instances. You can leverage this capability for use cases such as running emulators for mobile applications, simulating in-vehicle hardware for automobiles, and running Windows Subsystem for Linux on Windows workstations.
  • Server-Side Encryption by default in Amazon Aurora – Amazon Aurora further strengthens your security posture by automatically applying server-side encryption by default to all new databases clusters using AWS-owned keys. This encryption is fully managed, transparent to users, and with no cost or performance impact.
  • Kiro in AWS GovCloud (US) Regions – You can use Kiro for the development teams behind government missions. Developers in regulated environments can now leverage Kiro’s agentic AI tool with the rigorous security controls required.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Additional updates
Here are some additional news items that you might find interesting:

  • Introducing Agent Plugins for AWS – You can see how new open-source Agent Plugins for AWS extend coding agents with skills for deploying applications to AWS. Using the deploy-on-aws plugin, you can generate architecture recommendations, cost estimates, and infrastructure-as-code directly from your coding agent.
  • A chat with Byron Cook on automated reasoning and trust in AI systems – You can hear how to verify AI systems doing the right thing using automated reasoning when they generate code or manage critical decisions. Byron Cook’s team has spent a decade proving correctness in AWS and apply those techniques to agentic systems.
  • Best practices for deploying AWS DevOps Agent in production – You can read best practices for setting up DevOps Agent Spaces that balance investigation capability with operational efficiency. According to Swami Sivasubramanian, AWS DevOps Agent, a frontier agent that resolves and proactively prevents incidents, has handled thousands of escalations, with an estimated root cause identification rate of over 86% within Amazon.

From AWS community
Here are my personal favorite posts from AWS community:

Join the AWS Builder Center to connect with community, share knowledge, and access content that supports your development.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Summits – Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
  • Amazon Nova AI Hackathon – Join developers worldwide to build innovative generative AI solutions using frontier foundation models and compete for $40,000 in prizes across five categories including agentic AI, multimodal understanding, UI automation, and voice experiences during this six-week challenge from February 2nd to March 16th, 2026.
  • AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Ahmedabad (February 28), JAWS Days in Tokyo (March 7), Chennai (March 7), Slovakia (March 11), and Pune (March 21).

Browse here for upcoming AWS led in-person and virtual events, startup events, and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Amazon EC2 Hpc8a Instances powered by 5th Gen AMD EPYC processors are now available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-ec2-hpc8a-instances-powered-by-5th-gen-amd-epyc-processors-are-now-available/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) Hpc8a instances, a new high performance computing (HPC) optimized instance type powered by latest 5th Generation AMD EPYC processors with a maximum frequency of up to 4.5 GHz. These instances are ideal for compute-intensive tightly coupled HPC workloads, including computational fluid dynamics, simulations for faster design iterations, high-resolution weather modeling within tight operational windows, and complex crash simulations that require rapid time-to-results.

The new Hpc8a instances deliver up to 40% higher performance, 42% greater memory bandwidth, and up to 25% better price-performance compared to previous generation Hpc7a instances. Customers benefit from the high core density, memory bandwidth, and low-latency networking that helped them scale efficiently and reduce job completion times for their compute-intensive simulation workloads.

Hpc8a instances
Hpc8a instances are available with 192 cores, 768 GiB memory, and 300 Gbps Elastic Fabric Adapter (EFA) networking to run applications requiring high levels of inter node communications at scale.

Instance Name Physical Cores Memory (Gib) EFA Network Bandwidth (Gbps) Network Bandwidth (Gbps) Attached Storage
Hpc8a.96xlarge 192 768 Up to 300 75 EBS Only

Hpc8a instances are available in a single 96xlarge size with a 1:4 core-to-memory ratio. You will have the capability to right size based on HPC workload requirements by customizing the number of cores needed at launch instances. These instances also use sixth-generation AWS Nitro cards, which offload CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

You can use Hpc8a instances with AWS ParallelCluster and AWS Parallel Computing Service (AWS PCS) to simplify workload submission and cluster creation and Amazon FSx for Lustre for sub-millisecond latencies and up to hundreds of gigabytes per second of throughput for storage. To achieve the best performance for HPC workloads, these instances have Simultaneous Multithreading (SMT) disabled.

Now available
Amazon EC2 Hpc8a instances are now available in US East (Ohio) and Europe (Stockholm) AWS Regions. For Regional availability and a future roadmap, search the instance type in the CloudFormation resources tab of AWS Capabilities by Region.

You can purchase these instances as On-Demand Instances and Savings Plan. To learn more, visit the Amazon EC2 Pricing page.

Give Hpc8a instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 Hpc8a instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Announcing Amazon SageMaker Inference for custom Amazon Nova models

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-amazon-sagemaker-inference-for-custom-amazon-nova-models/

Since we launched Amazon Nova customization in Amazon SageMaker AI at AWS NY Summit 2025, customers have been asking for the same capabilities with Amazon Nova as they do when they customize open weights models in Amazon SageMaker Inference. They also wanted have more control and flexibility in custom model inference over instance types, auto-scaling policies, context length, and concurrency settings that production workloads demand.

Today, we’re announcing the general availability of custom Nova model support in Amazon SageMaker Inference, a production-grade, configurable, and cost-efficient managed inference service to deploy and scale full-rank customized Nova models. You can now experience an end-to-end customization journey to train Nova Micro, Nova Lite, and Nova 2 Lite models with reasoning capabilities using Amazon SageMaker Training Jobs or Amazon HyperPod and seamlessly deploy them with managed inference infrastructure of Amazon SageMaker AI.

With Amazon SageMaker Inference for custom Nova models, you can reduce inference cost through optimized GPU utilization using Amazon Elastic Compute Cloud (Amazon EC2) G5 and G6 instances over P5 instances, auto-scaling based on 5-minute usage patterns, and configurable inference parameters. This feature enables deployment of customized Nova models with continued pre-training, supervised fine-tuning, or reinforcement fine-tuning for your use cases. You can also set advanced configurations about context length, concurrency, and batch size for optimizing the latency-cost-accuracy tradeoff for your specific workloads.

Let’s see how to deploy customized Nova models on SageMaker AI real-time endpoints, configure inference parameters, and invoke your models for testing.

Deploy custom Nova models in SageMaker Inference
At AWS re:Invent 2025, we introduced new serverless customization in Amazon SageMaker AI for popular AI models including Nova models. With a few clicks, you can seamlessly select a model and customization technique, and handle model evaluation and deployment. If you already have a trained custom Nova model artifact, you can deploy the models on SageMaker Inference through the SageMaker Studio or SageMaker AI SDK.

In the SageMaker Studio, choose a trained Nova model in Models in your models in the Models menu. You can deploy the model by choosing Deploy button, SageMaker AI and Create new endpoint.

Choose the endpoint name, instance type, and advanced options such as instance count, max instance count, permission and networking, and Deploy button. At GA launch, you can use g5.12xlarge, g5.24xlarge, g5.48xlarge, g6.12xlarge, g6.24xlarge, g6.48xlarge, and p5.48xlarge instance types for the Nova Micro model, g5.24xlarge, g5.48xlarge, g6.24xlarge, g6.48xlarge, and p5.48xlarge for the Nova Lite model, and p5.48xlarge for the Nova 2 Lite model.

Creating your endpoint requires time to provision the infrastructure, download your model artifacts, and initialize the inference container.

After model deployment completes and the endpoint status shows InService, you can perform real-time inference using the new endpoint. To test the model, choose the Playground tab and input your prompt in the Chat mode.

You can also use the SageMaker AI SDK to create two resources: a SageMaker AI model object that references your Nova model artifacts, and an endpoint configuration that defines how the model will be deployed.

The following code creates a SageMaker AI model that references your Nova model artifacts:

# Create a SageMaker AI model
    model_response = sagemaker.create_model(
        ModelName= 'Nova-micro-ml-g5-12xlarge',
        PrimaryContainer={
            'Image': '123456789012.dkr.ecr.us-east-1.amazonaws.com/nova-inference-repo:v1.0.0',
            'ModelDataSource': {
                'S3DataSource': {
                   'S3Uri': 's3://your-bucket-name/path/to/model/artifacts/',
                   'S3DataType': 'S3Prefix',
                   'CompressionType': 'None'
                }
            },
            # Model Parameters
            'Environment': {
                'CONTEXT_LENGTH': 8000,
                'CONCURRENCY': 16,
                'DEFAULT_TEMPERATURE': 0.0,
                'DEFAULT_TOP_P': 1.0
            }
        },
        ExecutionRoleArn=SAGEMAKER_EXECUTION_ROLE_ARN,
        EnableNetworkIsolation=True
    )
    print("Model created successfully!")

Next, create an endpoint configuration that defines your deployment infrastructure and deploy your Nova model by creating a SageMaker AI real-time endpoint. This endpoint will host your model and provide a secure HTTPS endpoint for making inference requests.

# Create Endpoint Configuration
    production_variant = {
        'VariantName': 'primary',
        'ModelName': 'Nova-micro-ml-g5-12xlarge',
        'InitialInstanceCount': 1,
        'InstanceType': 'ml.g5.12xlarge',
    }
    
    config_response = sagemaker.create_endpoint_config(
        EndpointConfigName= 'Nova-micro-ml-g5-12xlarge-Config',
        ProductionVariants= production_variant
    )
    print("Endpoint configuration created successfully!")
    
# Deploy your Noval model
    endpoint_response = sagemaker.create_endpoint(
        EndpointName= 'Nova-micro-ml-g5-12xlarge-endpoint',
        EndpointConfigName= 'Nova-micro-ml-g5-12xlarge-Config'
    )
    print("Endpoint creation initiated successfully!")

After the endpoint is created, you can send inference requests to generate predictions from your custom Nova model. Amazon SageMaker AI supports synchronous endpoints for real-time with streaming/non-streaming modes and asynchronous endpoints for batch processing.

For example, the following code creates streaming completion format for text generation:

# Streaming chat request with comprehensive parameters
streaming_request = {
"messages": [
        {"role": "user", "content": "Compare our Q4 2025 actual spend against budget across all departments and highlight variances exceeding 10%"}
    ],
    "max_tokens": 512,
    "stream": True,
    "temperature": 0.7,
    "top_p": 0.95,
    "top_k": 40,
    "logprobs": True,
    "top_logprobs": 2,
    "reasoning_effort": "low",  # Options: "low", "high"
    "stream_options": {"include_usage": True}
}

invoke_nova_endpoint(streaming_request)

def invoke_nova_endpoint(request_body):
"""
    Invoke Nova endpoint with automatic streaming detection.
    
    Args:
        request_body (dict): Request payload containing prompt and parameters
    
    Returns:
        dict: Response from the model (for non-streaming requests)
        None: For streaming requests (prints output directly)
    """
    body = json.dumps(request_body)
    is_streaming = request_body.get("stream", False)
    
    try:
        print(f"Invoking endpoint ({'streaming' if is_streaming else 'non-streaming'})...")
        
        if is_streaming:
            response = runtime_client.invoke_endpoint_with_response_stream(
                EndpointName=ENDPOINT_NAME,
                ContentType='application/json',
                Body=body
            )
            
            event_stream = response['Body']
            for event in event_stream:
                if 'PayloadPart' in event:
                    chunk = event['PayloadPart']
                    if 'Bytes' in chunk:
                        data = chunk['Bytes'].decode()
                        print("Chunk:", data)
        else:
            # Non-streaming inference
            response = runtime_client.invoke_endpoint(
                EndpointName=ENDPOINT_NAME,
                ContentType='application/json',
                Accept='application/json',
                Body=body
            )
            
            response_body = response['Body'].read().decode('utf-8')
            result = json.loads(response_body)
            print("✅ Response received successfully")
            return result
    
    except ClientError as e:
        error_code = e.response['Error']['Code']
        error_message = e.response['Error']['Message']
        print(f"❌ AWS Error: {error_code} - {error_message}")
    except Exception as e:
        print(f"❌ Unexpected error: {str(e)}")

To use full code examples, visit Customizing Amazon Nova models on Amazon SageMaker AI. To learn more about best practices on deploying and managing models, visit Best Practices for SageMaker AI.

Now available
Amazon SageMaker Inference for custom Nova models is available today in US East (N. Virginia) and US West (Oregon) AWS Regions. For Regional availability and a future roadmap, visit the AWS Capabilities by Region.

The feature supports Nova Micro, Nova Lite, and Nova 2 Lite models with reasoning capabilities, running on EC2 G5, G6, and P5 instances with auto-scaling support. You pay only for the compute instances you use, with per-hour billing and no minimum commitments. For more information, visit Amazon SageMaker AI Pricing page.

Give it a try in Amazon SageMaker AI console and send feedback to AWS re:Post for SageMaker or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: Claude Opus 4.6 in Amazon Bedrock, AWS Builder ID Sign in with Apple, and more (February 9, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-opus-4-6-in-amazon-bedrock-aws-builder-id-sign-in-with-apple-and-more-february-9-2026/

Here are the notable launches and updates from last week that can help you build, scale, and innovate on AWS.

Last week’s launches
Here are the launches that got my attention this week.

Let’s start with news related to compute and networking infrastructure:

  • Introducing Amazon EC2 C8id, M8id, and R8id instances: These new Amazon EC2 C8id, M8id, and R8id instances are powered by custom Intel Xeon 6 processors. These instances offer up to 43% higher performance and 3.3x more memory bandwidth compared to previous generation instances.
  • AWS Network Firewall announces new price reductions: The service has added the hourly and data processing discounts on NAT Gateways that are service-chained with Network Firewall secondary endpoints. Additionally, AWS Network Firewall has removed additional data processing charges for Advanced Inspection, which enables Transport Layer Security (TLS) inspection of encrypted network traffic.
  • Amazon ECS adds Network Load Balancer support for Linear and Canary deployments: Applications that commonly use NLB, such as those requiring TCP/UDP-based connections, low latency, long-lived connections, or static IP addresses, can take advantage of managed, incremental traffic shifting natively from ECS when rolling out updates.
  • AWS Config now supports 30 new resource types: These range across key services including Amazon EKS, Amazon Q, and AWS IoT. This expansion provides greater coverage over your AWS environment, enabling you to more effectively discover, assess, audit, and remediate an even broader range of resources.
  • Amazon DynamoDB global tables now support replication across multiple AWS accounts: DynamoDB global tables are a fully managed, serverless, multi-Region, and multi-active database. With this new capability, you can replicate tables across AWS accounts and Regions to improve resiliency, isolate workloads at the account level, and apply distinct security and governance controls.
  • Amazon RDS now provides an enhanced console experience to connect to a database: The new console experience provides ready-made code snippets for Java, Python, Node.js, and other programming languages as well as tools like the psql command line utility. These code snippets are automatically adjusted based on your database’s authentication settings. For example, if your cluster uses IAM authentication, the generated code snippets will use token-based authentication to connect to the database. The console experience also includes integrated CloudShell access, offering the ability to connect to your databases directly from within the RDS console.

Then, I noticed three news items related to security and how you authenticate on AWS:

  • AWS Builder ID now supports Sign in with Apple: AWS Builder ID, your profile for accessing AWS applications including AWS Builder Center, AWS Training and Certification, AWS re:Post, AWS Startups, and Kiro, now supports sign-in with Apple as a social login provider. This expansion of sign-in options builds on the existing sign-in with Google capability, providing Apple users with a streamlined way to access AWS resources without managing separate credentials on AWS.
  • AWS STS now supports validation of select identity provider specific claims from Google, GitHub, CircleCI and OCI: You can reference these custom claims as condition keys in IAM role trust policies and resource control policies, expanding your ability to implement fine-grained access control for federated identities and help you establish your data perimeters. This enhancement builds upon IAM’s existing OIDC federation capabilities, which allow you to grant temporary AWS credentials to users authenticated through external OIDC-compatible identity providers.
  • AWS Management Console now displays Account Name on the Navigation bar for easier account identification: You now have an easy way to identify your accounts at a glance. You can now quickly distinguish between accounts visually using the account name that appears in the navigation bar for all authorized users in that account.
  • Amazon CloudFront announces mutual TLS support for origins: Now with origin mTLS support, you can implement a standardized, certificate-based authentication approach that eliminates operational burden. This enables organizations to enforce strict authentication for their proprietary content, ensuring that only verified CloudFront distributions can establish connections to backend infrastructure ranging from AWS origins and on-premises servers to third-party cloud providers and external CDNs.

Finally, there is not a single week without news around AI :

  • Claude Opus 4.6 now available in Amazon Bedrock: Opus 4.6 is Anthropic’s most intelligent model to date and a premier model for coding, enterprise agents, and professional work. Claude Opus 4.6 brings advanced capabilities to Amazon Bedrock customers, including industry-leading performance for agentic tasks, complex coding projects, and enterprise-grade workflows that require deep reasoning and reliability.
  • Structured outputs now available in Amazon Bedrock: Amazon Bedrock now supports structured outputs, a capability that provides consistent, machine-readable responses from foundation models that adhere to your defined JSON schemas. Instead of prompting for valid JSON and adding extra checks in your application, you can specify the format you want and receive responses that match it—making production workflows more predictable and resilient.

Upcoming AWS events
Check your calendars so that you can sign up for this upcoming event:

AWS Community Day Romania (April 23–24, 2026): This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.

If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.

Check back next Monday for another Weekly Roundup.

— seb
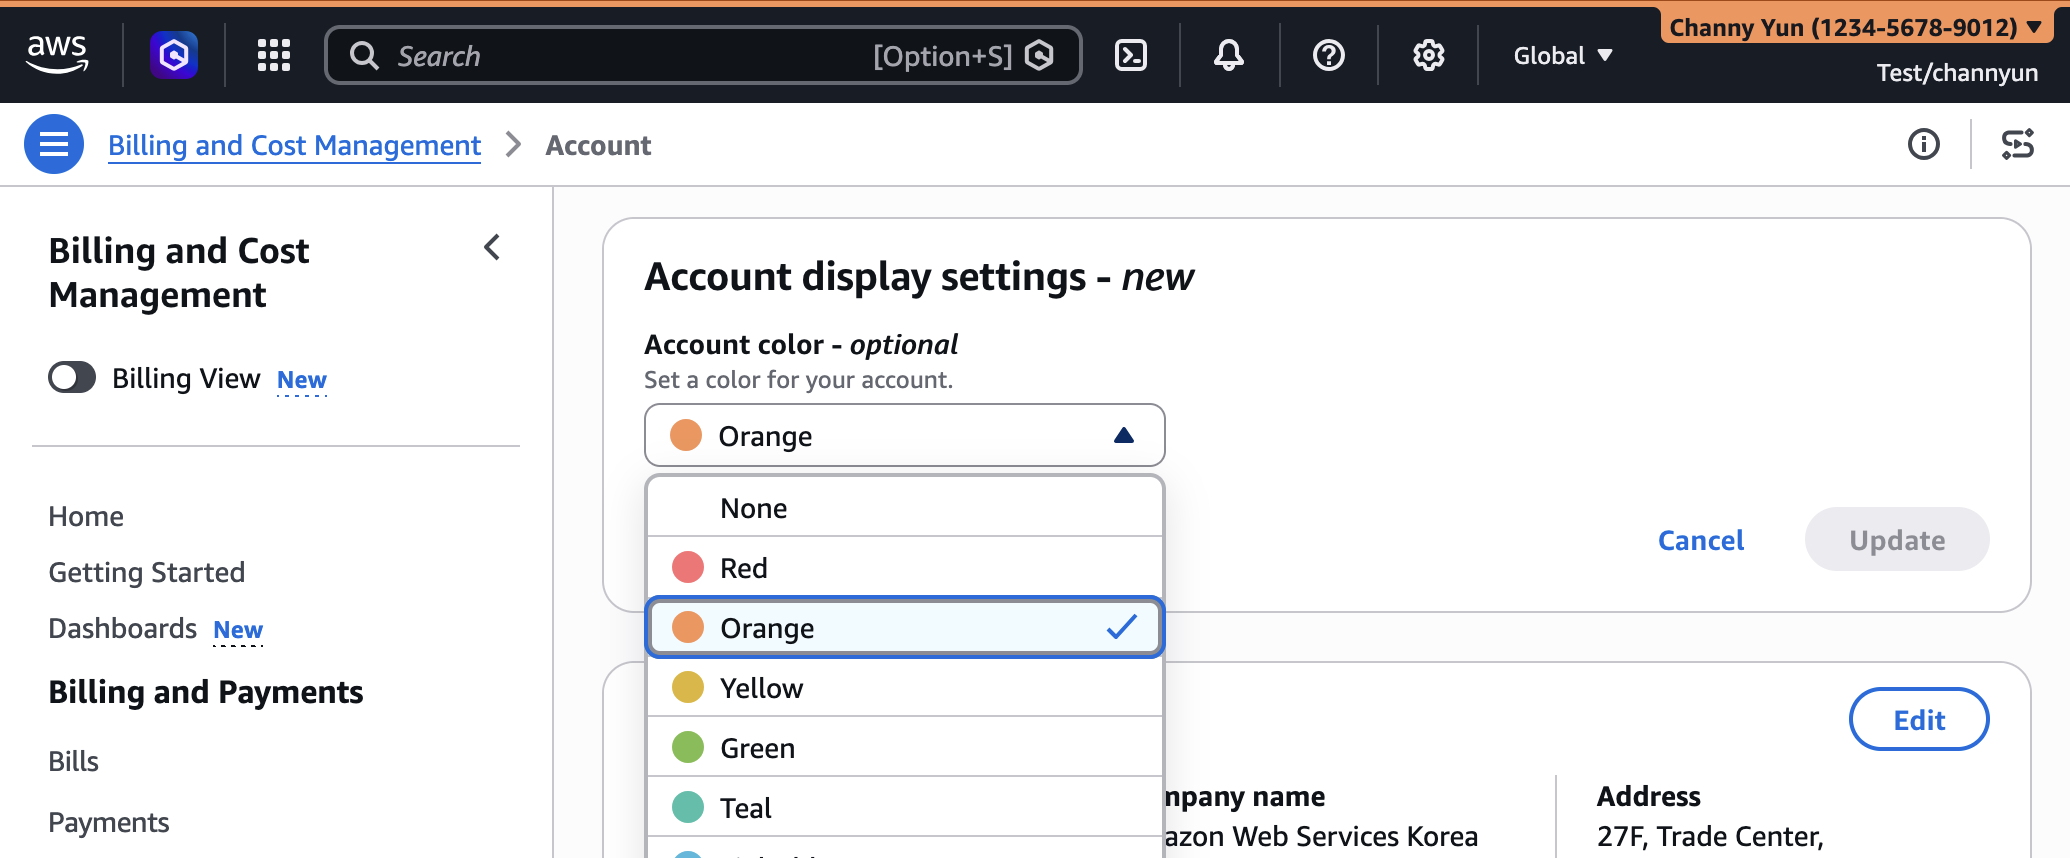
Amazon EC2 C8id, M8id, and R8id instances with up to 22.8 TB local NVMe storage are generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-ec2-c8id-m8id-and-r8id-instances-with-up-to-22-8-tb-local-nvme-storage-are-generally-available/

Last year, we launched the Amazon Elastic Compute Cloud (Amazon EC2) C8i instances, M8i instances, and R8i instances powered by custom Intel Xeon 6 processors available only on AWS with sustained all-core 3.9 GHz turbo frequency. They deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud.

Today we’re announcing new Amazon EC2 C8id, M8id, and R8id instances backed by up to 22.8TB of NVMe-based SSD block-level instance storage physically connected to the host server. These instances offer 3 times more vCPUs, memory and local storage compared to previous sixth-generation instances.

These instances deliver up to 43% higher compute performance and 3.3 times more memory bandwidth compared to previous sixth-generation instances. They also deliver up to 46% higher performance for I/O intensive database workloads, and up to 30% faster query results for I/O intensive real-time data analytics compared to previous sixth generation instances.

  • C8id instances are ideal for compute-intensive workloads, including those that need access to high-speed, low-latency local storage like video encoding, image manipulation, and other forms of media processing.
  • M8id instances are best for workloads that require a balance of compute and memory resources along with high-speed, low-latency local block storage, including data logging, media processing, and medium-sized data stores.
  • R8id instances are designed for memory-intensive workloads such as large-scale SQL and NoSQL databases, in-memory databases, large-scale data analytics, and AI inference.

C8id, M8id, and R8id instances now scale up to 96xlarge (versus 32xlarge sizes in the sixth generation) with up to 384 vCPUs, 3TiB of memory, and 22.8TB of local storage that make it easier to scale up applications and drive greater efficiencies. These instances also offer two bare metal sizes (metal-48xl and metal-96xl), allowing you to right size your instances and deploy your most performance sensitive workloads that benefit from direct access to physical resources.

The instances are available in 11 sizes per family, as well as two bare metal configurations each:

Instance Name vCPUs Memory (GiB) (C/M/R) Local NVMe storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
large 2 4/8/16* 1 x 118 Up to 12.5 Up to 10
xlarge 4 8/16/32* 1 x 237 Up to 12.5 Up to 10
2xlarge 8 16/32/64* 1 x 474 Up to 15 Up to 10
4xlarge 16 32/64/128* 1 x 950 Up to 15 Up to 10
8xlarge 32 64/128/256* 1 x 1,900 15 10
12xlarge 48 96/192/384* 1 x 2,850 22.5 15
16xlarge 64 128/256/512* 1 x 3,800 30 20
24xlarge 96 192/384/768* 2 x 2,850 40 30
32xlarge 128 256/512/1024* 2 x 3,800 50 40
48xlarge 192 384/768/1536* 3 x 3,800 75 60
96xlarge 384 768/1536/3072* 6 x 3,800 100 80
metal-48xl 192 384/768/1536* 3 x 3,800 75 60
metal-96xl 384 768/1536/3072* 6 x 3,800 100 80

*Memory values are for C8id/M8id/R8id respectively.

These instances support the Instance Bandwidth Configuration (IBC) feature like other eighth-generation instance types, offering flexibility to allocate resources between network and Amazon Elastic Block Store (Amazon EBS) bandwidth. You can scale network or EBS bandwidth by 25%, allocating resources optimally for each workload. These instances also use sixth-generation AWS Nitro cards offloading CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

You can use any Amazon Machine Images (AMIs) that include drivers for the Elastic Network Adapter (ENA) and NVMe to fully utilize the performance and capabilities. All current generation AWS Windows and Linux AMIs come with the AWS NVMe driver installed by default. If you use an AMI that does not have the AWS NVMe driver, you can manually install AWS NVMe drivers.

As I noted in my previous blog post, here are a couple of things to remind you about the local NVMe storage on these instances:

  • You don’t have to specify a block device mapping in your AMI or during the instance launch; the local storage will show up as one or more devices (/dev/nvme[0-26]n1 on Linux) after the guest operating system has booted.
  • Each local NVMe device is hardware encrypted using the XTS-AES-256 block cipher and a unique key. Each key is destroyed when the instance is stopped or terminated.
  • Local NVMe devices have the same lifetime as the instance they are attached to and do not persist after the instance has been stopped or terminated.

To learn more, visit Amazon EBS volumes and NVMe in the Amazon EBS User Guide.

Now available
Amazon EC2 C8id, M8id and R8id instances are available in US East (N. Virginia), US East (Ohio), and US West (Oregon) AWS Regions. R8id instances are additionally available in Europe (Frankfurt) Region. For Regional availability and a future roadmap, search the instance type in the CloudFormation resources tab of AWS Capabilities by Region.

You can purchase these instances as On-Demand Instances, Savings Plans, and Spot Instances. These instances are also available as Dedicated Instances and Dedicated Hosts. To learn more, visit the Amazon EC2 Pricing page.

Give C8id, M8id, and R8id instances a try in the Amazon EC2 console. To learn more, visit the EC2 C8i instances, M8i instances, and R8i instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS IAM Identity Center now supports multi-Region replication for AWS account access and application use

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-iam-identity-center-now-supports-multi-region-replication-for-aws-account-access-and-application-use/

Today, we’re announcing the general availability of AWS IAM Identity Center multi-Region support to enable AWS account access and managed application use in additional AWS Regions.

With this feature, you can replicate your workforce identities, permission sets, and other metadata in your organization instance of IAM Identity Center connected to an external identity provider (IdP), such as Microsoft Entra ID and Okta, from its current primary Region to additional Regions for improved resiliency of AWS account access.

You can also deploy AWS managed applications in your preferred Regions, close to application users and datasets for improved user experience or to meet data residency requirements. Your applications deployed in additional Regions access replicated workforce identities locally for optimal performance and reliability.

When you replicate your workforce identities to an additional Region, your workforce gets an active AWS access portal endpoint in that Region. This means that in the unlikely event of an IAM Identity Center service disruption in its primary Region, your workforce can still access their AWS accounts through the AWS access portal in an additional Region using already provisioned permissions. You can continue to manage IAM Identity Center configurations from the primary Region, maintaining centralized control.

Enable IAM Identity Center in multiple Regions
To get started, you should confirm that the AWS managed applications you’re currently using support customer managed AWS Key Management Service (AWS KMS) key enabled in AWS Identity Center. When we introduced this feature in October 2025, Seb recommended using multi-Region AWS KMS keys unless your company policies restrict you to single-Region keys. Multi-Region keys provide consistent key material across Regions while maintaining independent key infrastructure in each Region.
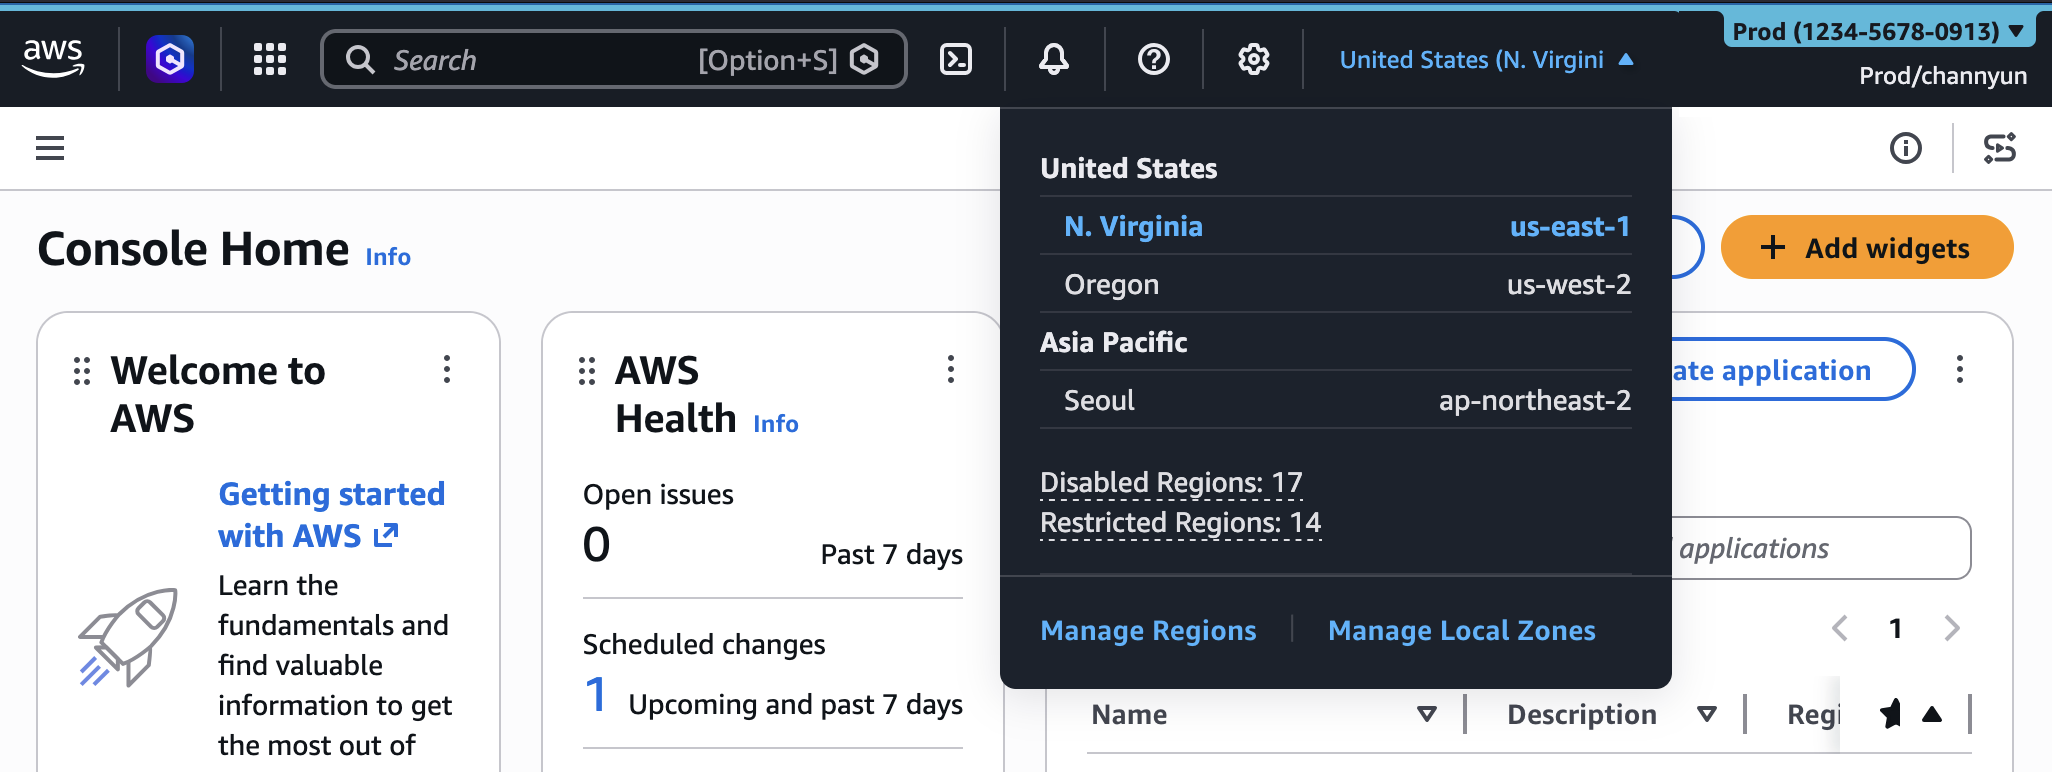
Before replicating IAM Identity Center to an additional Region, you must first replicate the customer managed AWS KMS key to that Region and configure the replica key with the permissions required for IAM Identity Center operations. For instructions on creating multi-Region replica keys, refer to Create multi-Region replica keys in the AWS KMS Developer Guide.

Go to the IAM Identity Center console in the primary Region, for example, US East (N. Virginia), choose Settings in the left-navigation pane, and select the Management tab. Confirm that your configured encryption key is a multi-Region customer managed AWS KMS key. To add more Regions, choose Add Region.

You can choose additional Regions to replicate the IAM Identity Center in a list of the available Regions. When choosing an additional Region, consider your intended use cases, for example, data compliance or user experience.

If you want to run AWS managed applications that access datasets limited to a specific Region for compliance reasons, choose the Region where the datasets reside. If you plan to use the additional Region to deploy AWS applications, verify that the required applications support your chosen Region and deployment in additional Regions.

Choose Add Region. This starts the initial replication whose duration depends on the size of your Identity Center instance.

After the replication is completed, your users can access their AWS accounts and applications in this new Region. When you choose View ACS URLs, you can view SAML information, such as an Assertion Consumer Service (ACS) URL, about the primary and additional Regions.

How your workforce can use an additional Region
AWS Identity Center supports SAML single sign-on with external IdPs, such as Microsoft Entra ID and Okta. Upon authentication in the IdP, the user is redirected to the AWS access portal. To enable the user to be redirected to the AWS access portal in the newly added Region, you need to add the additional Region’s ACS URL to the IdP configuration.

The following screenshots show you how to do this in the Okta admin console:

Then, you can create a bookmark application in your identity provider for users to discover the additional Region. This bookmark app functions like a browser bookmark and contains only the URL to the AWS access portal in the additional Region.

You can also deploy AWS managed applications in additional Regions using your existing deployment workflows. Your users can access applications or accounts using the existing access methods, such as the AWS access portal, an application link, or through the AWS Command Line Interface (AWS CLI).

To learn more about which AWS managed applications support deployment in additional Regions, visit the IAM Identity Center User Guide.

Things to know
Here are key considerations to know about this feature:

  • Consideration – To take advantage of this feature at launch, you must be using an organization instance of IAM Identity Center connected to an external IdP. Also, the primary and additional Regions must be enabled by default in an AWS account. Account instances of IAM Identity Center, and the other two identity sources (Microsoft Active Directory and IAM Identity Center directory) are presently not supported.
  • Operation – The primary Region remains the central place for managing workforce identities, account access permissions, external IdP, and other configurations. You can use the IAM Identity Center console in additional Regions with a limited feature set. Most operations are read-only, except for application management and user session revocation.
  • Monitoring – All workforce actions are emitted in AWS CloudTrail in the Region where the action was performed. This feature enhances account access continuity. You can set up break-glass access for privileged users to access AWS if the external IdP has a service disruption.

Now available
AWS IAM Identity Center multi-Region support is now available in the 17 enabled-by-default commercial AWS Regions. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. You can use this feature at no additional cost. Standard AWS KMS charges apply for storing and using customer managed keys.

Give it a try in the AWS Identity Center console. To learn more, visit the IAM Identity Center User Guide and send feedback to AWS re:Post for Identity Center or through your usual AWS Support contacts.

— Channy