Tag Archives: Uncategorized

Friday Squid Blogging: Interview with a Squid Researcher

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/friday-squid-blogging-interview-with-a-squid-researcher.html

Interview with Mike Vecchione, Curator of Cephalopoda — now that’s a job title — at the Smithsonian Museum of National History.

One reason they’re so interesting is they are intelligent invertebrates. Almost everything that we think of as being intelligent — parrots, dolphins, etc. — are vertebrates, so their brains are built on the same basic structure. Whereas cephalopod brains have evolved from a ring of nerves around the esophagus. It’s a form of intelligence that’s completely independent from ours.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

The Legal Risks of Security Research

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/the-legal-risks-of-security-research.html

Sunoo Park and Kendra Albert have published “A Researcher’s Guide to Some Legal Risks of Security Research.”

From a summary:

Such risk extends beyond anti-hacking laws, implicating copyright law and anti-circumvention provisions (DMCA §1201), electronic privacy law (ECPA), and cryptography export controls, as well as broader legal areas such as contract and trade secret law.

Our Guide gives the most comprehensive presentation to date of this landscape of legal risks, with an eye to both legal and technical nuance. Aimed at researchers, the public, and technology lawyers alike, its aims both to provide pragmatic guidance to those navigating today’s uncertain legal landscape, and to provoke public debate towards future reform.

Comprehensive, and well worth reading.

Here’s a Twitter thread by Kendra.

Tracking Users on Waze

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/tracking-users-on-waze.html

A security researcher discovered a wulnerability in Waze that breaks the anonymity of users:

I found out that I can visit Waze from any web browser at waze.com/livemap so I decided to check how are those driver icons implemented. What I found is that I can ask Waze API for data on a location by sending my latitude and longitude coordinates. Except the essential traffic information, Waze also sends me coordinates of other drivers who are nearby. What caught my eyes was that identification numbers (ID) associated with the icons were not changing over time. I decided to track one driver and after some time she really appeared in a different place on the same road.

The vulnerability has been fixed. More interesting is that the researcher was able to de-anonymize some of the Waze users, proving yet again that anonymity is hard when we’re all so different.

The NSA is Refusing to Disclose its Policy on Backdooring Commercial Products

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/the-nsa-is-refusing-to-disclose-its-policy-on-backdooring-commercial-products.html

Senator Ron Wyden asked, and the NSA didn’t answer:

The NSA has long sought agreements with technology companies under which they would build special access for the spy agency into their products, according to disclosures by former NSA contractor Edward Snowden and reporting by Reuters and others.

These so-called back doors enable the NSA and other agencies to scan large amounts of traffic without a warrant. Agency advocates say the practice has eased collection of vital intelligence in other countries, including interception of terrorist communications.

The agency developed new rules for such practices after the Snowden leaks in order to reduce the chances of exposure and compromise, three former intelligence officials told Reuters. But aides to Senator Ron Wyden, a leading Democrat on the Senate Intelligence Committee, say the NSA has stonewalled on providing even the gist of the new guidelines.

[…]

The agency declined to say how it had updated its policies on obtaining special access to commercial products. NSA officials said the agency has been rebuilding trust with the private sector through such measures as offering warnings about software flaws.

“At NSA, it’s common practice to constantly assess processes to identify and determine best practices,” said Anne Neuberger, who heads NSA’s year-old Cybersecurity Directorate. “We don’t share specific processes and procedures.”

Three former senior intelligence agency figures told Reuters that the NSA now requires that before a back door is sought, the agency must weigh the potential fallout and arrange for some kind of warning if the back door gets discovered and manipulated by adversaries.

The article goes on to talk about Juniper Networks equipment, which had the NSA-created DUAL_EC PRNG backdoor in its products. That backdoor was taken advantage of by an unnamed foreign adversary.

Juniper Networks got into hot water over Dual EC two years later. At the end of 2015, the maker of internet switches disclosed that it had detected malicious code in some firewall products. Researchers later determined that hackers had turned the firewalls into their own spy tool here by altering Juniper’s version of Dual EC.

Juniper said little about the incident. But the company acknowledged to security researcher Andy Isaacson in 2016 that it had installed Dual EC as part of a “customer requirement,” according to a previously undisclosed contemporaneous message seen by Reuters. Isaacson and other researchers believe that customer was a U.S. government agency, since only the U.S. is known to have insisted on Dual EC elsewhere.

Juniper has never identified the customer, and declined to comment for this story.

Likewise, the company never identified the hackers. But two people familiar with the case told Reuters that investigators concluded the Chinese government was behind it. They declined to detail the evidence they used.

Okay, lots of unsubstantiated claims and innuendo here. And Neuberger is right; the NSA shouldn’t share specific processes and procedures. But as long as this is a democratic country, the NSA has an obligation to disclose its general processes and procedures so we all know what they’re doing in our name. And if it’s still putting surveillance ahead of security.

Reverse-Engineering the Redactions in the Ghislaine Maxwell Deposition

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/reverse-engineering-the-redactions-in-the-ghislaine-maxwell-deposition.html

Slate magazine was able to cleverly read the Ghislaine Maxwell deposition and reverse-engineer many of the redacted names.

We’ve long known that redacting is hard in the modern age, but most of the failures to date have been a result of not realizing that covering digital text with a black bar doesn’t always remove the text from the underlying digital file. As far as I know, this reverse-engineering technique is new.

EDITED TO ADD: A similar technique was used in 1991 to recover the Dead Sea Scrolls.

Introducing retry strategies for AWS Batch

Post Syndicated from Emma White original https://aws.amazon.com/blogs/compute/introducing-retry-strategies-for-aws-batch/

This post is contributed by Christian Kniep, Sr. Developer Advocate, HPC and AWS Batch.

Scientists, researchers, and engineers are using AWS Batch to run workloads reliably at scale, and to offload the undifferentiated heavy lifting in their day-to-day work. But even with a slight chance of failure in the stack, the act of mitigating these failures reminds customers that infrastructure, middleware and software are not error proof.

Many customers use Amazon EC2 Spot Instances to save up to 90% on their computing cost by leveraging unused EC2 capacity. If unused EC2 capacity is unavailable, an EC2 Spot Instance can be reclaimed by EC2. While AWS Batch takes care of rescheduling the job on a different instance, this rescheduling should not be handled differently depending on whether it is an application failure or some infrastructure event interrupting the job.

Starting today, customers can define how many retries are performed in cases where a task does not finish correctly. AWS Batch now allows customers define custom retry conditions, so that failures like an interruption of an instance or an infrastructure agent are handled differently, and do not just exhaust the number of retries attempted.

In this blog, I show the benefits of custom retry with AWS Batch by using different error codes from a job to control whether it should be retried. I will also demonstrate how to handle infrastructure events like a failing container image download, or an EC2 Spot interruption.

Example setup

To showcase this new feature, I use the AWS Command Line Interface (AWS CLI) to set up the following:

  1. IAMroles, policies, and profiles to grant access and permissions
  2. A compute environment (CE) to provide the compute resources to run jobs
  3. A job queue, which supervises the job execution and schedules jobs on the CE
  4. Job definitions with different retry strategies,which use a simple job to demonstrate how the new configuration can be applied

Once those tasks are completed, I submit jobs to show how you can handle different scenarios, such as infrastructure failure, application handling via error code or a middleware event.

Prerequisite

To make things easier, I first set up a couple of environment variables to have the information available for later use. I use the following code to set up the environment variables:

# in case it is not already installed
sudo yum install -y jq 
export MD_URL=http://169.254.169.254/latest/meta-data
export IFACE=$(curl -s ${MD_URL}/network/interfaces/macs/)
export SUBNET_ID=$(curl -s ${MD_URL}/network/interfaces/macs/${IFACE}/subnet-id)
export VPC_ID=$(curl -s ${MD_URL}/network/interfaces/macs/${IFACE}/vpc-id)
export AWS_REGION=$(curl -s ${MD_URL}/placement/availability-zone | sed 's/[a-z]$//')
export AWS_ACCT_ID=$(curl -s ${MD_URL}/identity-credentials/ec2/info |jq -r .AccountId)
export AWS_SG_DEFAULT=$(aws ec2 describe-security-groups \
--filters Name=group-name,Values=default \
|jq -r '.SecurityGroups[0].GroupId')

IAM

When using the AWS Management Console, I must create IAM roles manually.

Trust policies

IAM roles are defined to be used by an individual service. In the simplest case, I want a role to be used by Amazon EC2 – the service that provides the compute capacity in the cloud. The definition of which entity is able to use an IAM role is called a Trust Policy. To set up a Trust Policy for an IAM role, I use the following code snippet:

cat > ec2-trust-policy.json << EOF
{
  "Version": "2012-10-17",
  "Statement": [{
    "Effect": "Allow",
    "Principal": {
      "Service": "ec2.amazonaws.com"
    },
    "Action": "sts:AssumeRole"
  }]
}
EOF

Instance role

With the IAM trust policy, I can now create an ecsInstanceRole and attach the pre-defined policy AmazonEC2ContainerServiceforEC2Role. This allows an instance to interact with Amazon ECS.

aws iam create-role --role-name ecsInstanceRole \
 --assume-role-policy-document file://ec2-trust-policy.json
aws iam create-instance-profile --instance-profile-name ecsInstanceProfile
aws iam add-role-to-instance-profile \
    --instance-profile-name ecsInstanceProfile \
    --role-name ecsInstanceRole
aws iam attach-role-policy --role-name ecsInstanceRole \
 --policy-arn arn:aws:iam::aws:policy/service-role/AmazonEC2ContainerServiceforEC2Role

Service role

The AWS Batch service uses a role to interact with different services. The trust relationship reflects that the AWS Batch service is going to assume this role. I can set up this role with the following logic:

cat > svc-trust-policy.json << EOF
{
  "Version": "2012-10-17",
  "Statement": [{
    "Effect": "Allow",
    "Principal": {
      "Service": "batch.amazonaws.com"
    },
    "Action": "sts:AssumeRole"
  }]
}
EOF
aws iam create-role --role-name AWSBatchServiceRole \
--assume-role-policy-document file://svc-trust-policy.json
aws iam attach-role-policy --role-name AWSBatchServiceRole \
--policy-arn arn:aws:iam::aws:policy/service-role/AWSBatchServiceRole

At this point, I have created the IAM roles and policies so that the instances and services are able to interact with the AWS API operations, including trust policies to define which services are meant to use them. EC2 for the ecsInstanceRole and the AWSBatchServiceRole for the AWS Batch service itself.

Compute environment

Now, I am going to create a CE, which will launch instances to run the example jobs.

cat > compute-environment.json << EOF
{
  "computeEnvironmentName": "compute-0",
  "type": "MANAGED",
  "state": "ENABLED",
  "computeResources": {
    "type": "SPOT",
    "allocationStrategy": "SPOT_CAPACITY_OPTIMIZED",
    "minvCpus": 2,
    "maxvCpus": 32,
    "desiredvCpus": 4,
    "instanceTypes": [ "m5.xlarge","m5.2xlarge","m4.xlarge","m4.2xlarge","m5a.xlarge","m5a.2xlarge"],
    "subnets": ["${SUBNET_ID}"],
    "securityGroupIds": ["${AWS_SG_DEFAULT}"],
    "instanceRole": "arn:aws:iam::${AWS_ACCT_ID}:instance-profile/ecsInstanceRole",
    "tags": {"Name": "aws-batch-instances"},
    "ec2KeyPair": "batch-ssh-key",
    "bidPercentage": 0
  },
  "serviceRole": "arn:aws:iam::${AWS_ACCT_ID}:role/AWSBatchServiceRole"
}
EOF
aws batch create-compute-environment --cli-input-json file:// compute-environment.json 

Once this is complete, my compute environment begins to launch instances. This takes a few minutes. I can use the following command to check on the status of the compute environment whenever I want:

aws batch describe-compute-environments |jq '.computeEnvironments[] |select(.computeEnvironmentName=="compute-0")'

The command uses jq to filter the output to only show the compute environment I just created.

Job queue

Now that I have my compute environment up and running, I can create a job queue, which accepts job submissions and schedules the jobs to the compute environment.

cat > job-queue.json << EOF
{
  "jobQueueName": "queue-0",
  "state": "ENABLED",
  "priority": 1,
  "computeEnvironmentOrder": [{
    "order": 0,
    "computeEnvironment": "compute-0"
  }]
}
EOF
aws batch create-job-queue --cli-input-json file://job-queue.json

Job definition

The job definition is used as a template for jobs. It is referenced in a job submission to specify the defaults of a job configuration, while some of the parameters can be overwritten when you submit.

Within the job definition, different retry strategies can be configured along with a maximum number of attempts for the job.
Three possible conditions can be used:

  • onExitCode will evaluate non-zero exit codes
  • onReason matched against middleware errors
  • onStatusReason can be used to react to infrastructure events such as an instance termination

Different conditions are assigned an action to either EXIT or RETRY the job. Important to note, that a job finishing with an exit code of zero will EXIT the job and not evaluate the retry condition. The default behavior for all non-zero exit code is the following:

{
  "onExitCode" : ""
  "onStatusReason" : ""
  "onReason" : "*"
  "action": retry
}

This condition retries every job that does not succeed (exit code 0) until the attempts are exhausted.

Spot Instance interruptions

AWS Batch works great with Spot Instances and customers are using this to reduce their compute cost. If Spot Instances become unavailable, instances are reclaimed by EC2, which can lead to one or more of my hosts being shut down. When this happens, the jobs running on those hosts are shut down due to an infrastructure event, not an application failure. Previously, separating these kinds of events from one another was only possible by catching the notification on the instance itself or through CloudWatch Events. Now with customer retry, you don’t have to rely on instance notifications or CloudWatch Events.

Using the job definition below, the job is restarted if the instance running the job gets shut down, which includes the termination due to a Spot Instance reclaim. The additional condition makes sure that the job exits whenever the exit code is not zero, otherwise the job would be rescheduled until the attempts are exhausted (see default behavior above).

cat > jdef-spot..json << EOF
{
    "jobDefinitionName": "spot",
    "type": "container",
    "containerProperties": {
        "image": "alpine:latest",
        "vcpus": 2,
        "memory": 256,
        "command":  ["sleep","600"],
        "readonlyRootFilesystem": false
    },
    "retryStrategy": { 
        "attempts": 5,
        "evaluateOnExit": 
        [{
            "onStatusReason" :"Host EC2*",
            "action": "RETRY"
        },{
  		  "onReason" : "*"
            "action": "EXIT"
        }]
    }
}
EOF
aws batch register-job-definition --cli-input-json file://jdef-spot.json

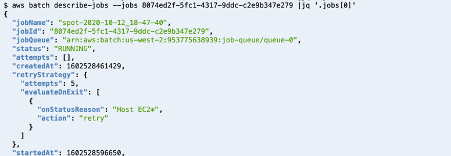
To simulate a Spot Instances reclaim, I submit a job, and manually shut down the host the job is running on. This triggers my condition to ask AWS Batch to make 5 attempts to finish the job before it marks the job a failure.

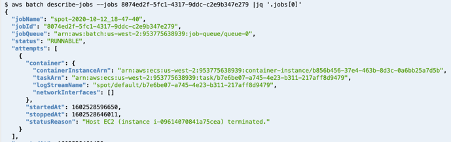
When I use the AWS CLI to describe my job, it displays the number of attempts to retry.

By shutting down my instance, the job returns to the status RUNNABLE and will be scheduled again until it succeeds or reaches the maximum attempts defined.

Exit code mitigation

I can also use the exit code to decide which mitigation I want to use based on the exit code of the job script or application itself.

To illustrate this, I can create a new job definition that uses a container image that exits on a random exit code between 0 and 3. Traditionally, an exit code of 0 means success, and won’t trigger this retry strategy. For all other (nonzero) exit codes the retry strategy is evaluated. In my example, 1 or 2 reflect situations where a retry is needed, but an exit code of 3 means that AWS Batch should let the job fail.

cat > jdef-randomEC.json << EOF
{
    "jobDefinitionName": "randomEC",
    "type": "container",
    "containerProperties": {
        "image": "qnib/random-ec:2020-10-13.3",
        "vcpus": 2,
        "memory": 256,
        "readonlyRootFilesystem": false
    },
    "retryStrategy": { 
        "attempts": 10,
        "evaluateOnExit": 
        [{
            "onExitCode": "1",
            "action": "RETRY"
        },{
            "onExitCode": "2",
            "action": "RETRY"
        },{
            "onExitCode": "3",
            "action": "EXIT"
        }]
    }
}
EOF
aws batch register-job-definition --cli-input-json file://jdef-randomEC.json

A submitted job retries until the exit code 0 is successful, 3 for a failure or the attempts are exhausted (in this case, 10 of them).

aws batch submit-job  --job-name randomEC-$(date +"%F_%H-%M-%S") --job-queue queue-0   --job-definition randomEC:1

The output of a job submission shows the job name and the job id.

In case the exit code is 1, and the job will be requeued.

Container image pull failure

The first example showed an error on the infrastructure layer and the second showed how to handle errors on the application layer. In this last example, I show how to handle errors that are introduced in the middleware layer, in this case: the container daemon.

It might happen if your Docker registry is down or having issues. To demonstrate this, I used an image name that is not present in the registry. In that case, the job should not get rescheduled to fail again immediately.

The following job definition again defines 10 attempts for a job, except when the container cannot be pulled. This leads to a direct failure of the job.

cat > jdef-noContainer.json << EOF
{
    "jobDefinitionName": "noContainer",
    "type": "container",
    "containerProperties": {
        "image": "no-container-image",
        "vcpus": 2,
        "memory": 256,
        "readonlyRootFilesystem": false
    },
    "retryStrategy": { 
        "attempts": 10,
        "evaluateOnExit": 
        [{
            "onReason": "CannotPullContainerError:*",
            "action": "EXIT"
        }]
    }
}
EOF
aws batch register-job-definition --cli-input-json file://jdef-noContainer.json

Note that the job defines an image name (“no-container-image”) which is not present in the registry. The job is set up to fail when trying to download the image, and will do so repeatedly, if AWS Batch keeps trying.

Even though the job definition has 10 attempts configured for this job, it fell straight through to FAILED as the retry strategy sets the action exit when a CannotPullContainerError occurs. Many of the error codes I can create conditions for are documented in the Amazon ECS user guide (e.g. task error codes / container pull error).

Conclusion

In this blog post, I showed three different scenarios that leverage the new custom retry features in AWS Batch to control when a job should exit or get rescheduled.

By defining retry strategies you can react to an infrastructure event (like an EC2 Spot interruption), an application signal (via the exit code), or an event within the middleware (like a container image not being available).

This new feature allows you to have fine grained control over how your jobs react to different error scenarios.

IMSI-Catchers from Canada

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/imsi-catchers-from-canada.html

Gizmodo is reporting that Harris Corp. is no longer selling Stingray IMSI-catchers (and, presumably, its follow-on models Hailstorm and Crossbow) to local governments:

L3Harris Technologies, formerly known as the Harris Corporation, notified police agencies last year that it planned to discontinue sales of its surveillance boxes at the local level, according to government records. Additionally, the company would no longer offer access to software upgrades or replacement parts, effectively slapping an expiration date on boxes currently in use. Any advancements in cellular technology, such as the rollout of 5G networks in most major U.S. cities, would render them obsolete.

The article goes on to talk about replacement surveillance systems from the Canadian company Octasic.

Octasic’s Nyxcell V800 can target most modern phones while maintaining the ability to capture older GSM devices. Florida’s state police agency described the device, made for in-vehicle use, as capable of targeting eight frequency bands including GSM (2G), CDMA2000 (3G), and LTE (4G).

[…]

A 2018 patent assigned to Octasic claims that Nyxcell forces a connection with nearby mobile devices when its signal is stronger than the nearest legitimate cellular tower. Once connected, Nyxcell prompts devices to divulge information about its signal strength relative to nearby cell towers. These reported signal strengths (intra-frequency measurement reports) are then used to triangulate the position of a phone.

Octasic appears to lean heavily on the work of Indian engineers and scientists overseas. A self-published biography of the company notes that while the company is headquartered in Montreal, it has “R&D facilities in India,” as well as a “worldwide sales support network.” Nyxcell’s website, which is only a single page requesting contact information, does not mention Octasic by name. Gizmodo was, however, able to recover domain records identifying Octasic as the owner.

New Report on Police Decryption Capabilities

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/new-report-on-police-decryption-capabilities.html

There is a new report on police decryption capabilities: specifically, mobile device forensic tools (MDFTs). Short summary: it’s not just the FBI that can do it.

This report documents the widespread adoption of MDFTs by law enforcement in the United States. Based on 110 public records requests to state and local law enforcement agencies across the country, our research documents more than 2,000 agencies that have purchased these tools, in all 50 states and the District of Columbia. We found that state and local law enforcement agencies have performed hundreds of thousands of cellphone extractions since 2015, often without a warrant. To our knowledge, this is the first time that such records have been widely disclosed.

Lots of details in the report. And in this news article:

At least 49 of the 50 largest U.S. police departments have the tools, according to the records, as do the police and sheriffs in small towns and counties across the country, including Buckeye, Ariz.; Shaker Heights, Ohio; and Walla Walla, Wash. And local law enforcement agencies that don’t have such tools can often send a locked phone to a state or federal crime lab that does.

[…]

The tools mostly come from Grayshift, an Atlanta company co-founded by a former Apple engineer, and Cellebrite, an Israeli unit of Japan’s Sun Corporation. Their flagship tools cost roughly $9,000 to $18,000, plus $3,500 to $15,000 in annual licensing fees, according to invoices obtained by Upturn.

New Chair and Trustees of the Raspberry Pi Foundation

Post Syndicated from Philip Colligan original https://www.raspberrypi.org/blog/new-chair-and-trustees-foundation/

I am delighted to share the news that we have appointed a new Chair and Trustees of the Raspberry Pi Foundation. Between them, they bring an enormous range of experience and expertise to what is already a fantastic Board of Trustees, and I am really looking forward to working with them.

New Chair of the Board of Trustees: John Lazar 

John Lazar has been appointed as the new Chair of the Board of Trustees. John is a software engineer and business leader who is focused on combining technology and entrepreneurship to generate lasting positive impact.

Formerly the Chairman and CEO of Metaswitch Networks, John is now an angel investor, startup mentor, non-executive chairman and board director, including serving as the Chair of What3Words. He is a Fellow of the Royal Academy of Engineering and played an active role in developing the programme of study for England’s school Computer Science curriculum. John has also spent many years working on tech-related non-profit initiatives in Africa and co-founded Enza Capital, which invests in early-stage African technology companies that solve pressing problems.

John takes over the Chair from David Cleevely, who has reached the end of his two three-year terms as Trustee and Chair of the Foundation. David has made a huge contribution to the Foundation over that time, and we are delighted that he will continue to be involved in our work as one of the founding members of the Supporters Club.

New Trustees: Amali de Alwis, Charles Leadbeater, Dan Labbad

Alongside John, we are welcoming three new Trustees to the Board of Trustees: 

  • Amali de Alwis is the UK Managing Director of Microsoft for Startups, and is the former CEO of Code First: Girls. She is also a Board member at Ada National College for Digital Skills, sits on the Diversity & Inclusion Board at the Institute of Coding, is an Advisory Board member at the Founders Academy, and was a founding member at Tech Talent Charter.
  • Charles Leadbeater is an independent author, a social entrepreneur, and a leading authority on innovation and creativity. He has advised companies, cities, and governments around the world on innovation strategy and has researched and written extensively on innovation in education. Charles is also a Trustee of the Paul Hamlyn Foundation.
  • Dan Labbad is Chief Executive and Executive Member of the Board of The Crown Estate. He was previously at Lendlease, where he was Chief Executive Officer of Europe from 2009. Dan is also a Director of The Hornery Institute and Ark Schools.

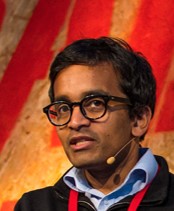
New Member: Suranga Chandratillake 

I am also delighted to announce that we have appointed Suranga Chandratillake as a Member of the Raspberry Pi Foundation. Suranga is a technologist, entrepreneur, and investor.

Suranga Chandratillake

He founded the intelligent search company blinkx and is now a General Partner at Balderton Capital. Suranga is a Fellow of the Royal Academy of Engineering and a World Economic Forum Young Global Leader, and he serves on the UK Government’s Council for Science and Technology.

What is a Board of Trustees anyway? 

As a charity, the Raspberry Pi Foundation is governed by a Board of Trustees that is ultimately responsible for what we do and how we are run. It is the Trustees’ job to make sure that we are focused on our mission, which for us means helping more people learn about computing, computer science, and related subjects. The Trustees also have all the usual responsibilities of company directors, including making sure that we use our resources effectively. As Chief Executive, I am accountable to the Board of Trustees. 

We’ve always been fortunate to attract the most amazing people to serve as Trustees and, as volunteers, they are incredibly generous with their time, sharing their expertise and experience on a wide range of issues. They are an important part of the team. Trustees serve for up to two terms of three years so that we always have fresh views and experience to draw on.

How do you appoint Trustees? 

Appointments to the Board of Trustees follow open recruitment and selection processes that are overseen by the Foundation’s Nominations Committee, supported by independent external advisers. Our aim is to appoint Trustees who bring different backgrounds, perspectives, and lived experience, as well as a range of skills. As with all appointments, we consider diversity at every aspect of the recruitment and selection processes.

Formally, Trustees are elected by the Foundation’s Members at our Annual General Meeting. This year’s AGM took place last week on Zoom. Members are also volunteers, and they play an important role in holding the Board of Trustees to account, helping to shape our strategy, and acting as advocates for our mission.

You can see the full list of Trustees and Members on our website.

The post New Chair and Trustees of the Raspberry Pi Foundation appeared first on Raspberry Pi.

NSA Advisory on Chinese Government Hacking

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/nsa-advisory-on-chinese-government-hacking.html

The NSA released an advisory listing the top twenty-five known vulnerabilities currently being exploited by Chinese nation-state attackers.

This advisory provides Common Vulnerabilities and Exposures (CVEs) known to be recently leveraged, or scanned-for, by Chinese state-sponsored cyber actors to enable successful hacking operations against a multitude of victim networks. Most of the vulnerabilities listed below can be exploited to gain initial access to victim networks using products that are directly accessible from the Internet and act as gateways to internal networks. The majority of the products are either for remote access (T1133) or for external web services (T1190), and should be prioritized for immediate patching.

Cybersecurity Visuals

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/cybersecurity-visuals.html

The Hewlett Foundation just announced its top five ideas in its Cybersecurity Visuals Challenge. The problem Hewlett is trying to solve is the dearth of good visuals for cybersecurity. A Google Images Search demonstrates the problem: locks, fingerprints, hands on laptops, scary looking hackers in black hoodies. Hewlett wanted to go beyond those tropes.

I really liked the idea, but find the results underwhelming. It’s a hard problem.

Hewlett press release.

Split-Second Phantom Images Fool Autopilots

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/split-second-phantom-images-fool-autopilots.html

Researchers are tricking autopilots by inserting split-second images into roadside billboards.

Researchers at Israel’s Ben Gurion University of the Negev … previously revealed that they could use split-second light projections on roads to successfully trick Tesla’s driver-assistance systems into automatically stopping without warning when its camera sees spoofed images of road signs or pedestrians. In new research, they’ve found they can pull off the same trick with just a few frames of a road sign injected on a billboard’s video. And they warn that if hackers hijacked an internet-connected billboard to carry out the trick, it could be used to cause traffic jams or even road accidents while leaving little evidence behind.

[…]

In this latest set of experiments, the researchers injected frames of a phantom stop sign on digital billboards, simulating what they describe as a scenario in which someone hacked into a roadside billboard to alter its video. They also upgraded to Tesla’s most recent version of Autopilot known as HW3. They found that they could again trick a Tesla or cause the same Mobileye device to give the driver mistaken alerts with just a few frames of altered video.

The researchers found that an image that appeared for 0.42 seconds would reliably trick the Tesla, while one that appeared for just an eighth of a second would fool the Mobileye device. They also experimented with finding spots in a video frame that would attract the least notice from a human eye, going so far as to develop their own algorithm for identifying key blocks of pixels in an image so that a half-second phantom road sign could be slipped into the “uninteresting” portions.

The paper:

Abstract: In this paper, we investigate “split-second phantom attacks,” a scientific gap that causes two commercial advanced driver-assistance systems (ADASs), Telsa Model X (HW 2.5 and HW 3) and Mobileye 630, to treat a depthless object that appears for a few milliseconds as a real obstacle/object. We discuss the challenge that split-second phantom attacks create for ADASs. We demonstrate how attackers can apply split-second phantom attacks remotely by embedding phantom road signs into an advertisement presented on a digital billboard which causes Tesla’s autopilot to suddenly stop the car in the middle of a road and Mobileye 630 to issue false notifications. We also demonstrate how attackers can use a projector in order to cause Tesla’s autopilot to apply the brakes in response to a phantom of a pedestrian that was projected on the road and Mobileye 630 to issue false notifications in response to a projected road sign. To counter this threat, we propose a countermeasure which can determine whether a detected object is a phantom or real using just the camera sensor. The countermeasure (GhostBusters) uses a “committee of experts” approach and combines the results obtained from four lightweight deep convolutional neural networks that assess the authenticity of an object based on the object’s light, context, surface, and depth. We demonstrate our countermeasure’s effectiveness (it obtains a TPR of 0.994 with an FPR of zero) and test its robustness to adversarial machine learning attacks.

Friday Squid Blogging: Chinese Squid Fishing Near the Galapagos

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/friday-squid-blogging-chinese-squid-fishing-near-the-galapagos.html

The Chinese have been illegally squid fishing near the Galapagos Islands.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

US Cyber Command and Microsoft Are Both Disrupting TrickBot

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/us-cyber-command-and-microsoft-are-both-disrupting-trickbot.html

Earlier this month, we learned that someone is disrupting the TrickBot botnet network.

Over the past 10 days, someone has been launching a series of coordinated attacks designed to disrupt Trickbot, an enormous collection of more than two million malware-infected Windows PCs that are constantly being harvested for financial data and are often used as the entry point for deploying ransomware within compromised organizations.

On Sept. 22, someone pushed out a new configuration file to Windows computers currently infected with Trickbot. The crooks running the Trickbot botnet typically use these config files to pass new instructions to their fleet of infected PCs, such as the Internet address where hacked systems should download new updates to the malware.

But the new configuration file pushed on Sept. 22 told all systems infected with Trickbot that their new malware control server had the address 127.0.0.1, which is a “localhost” address that is not reachable over the public Internet, according to an analysis by cyber intelligence firm Intel 471.

A few days ago, the Washington Post reported that it’s the work of US Cyber Command:

U.S. Cyber Command’s campaign against the Trickbot botnet, an army of at least 1 million hijacked computers run by Russian-speaking criminals, is not expected to permanently dismantle the network, said four U.S. officials, who spoke on the condition of anonymity because of the matter’s sensitivity. But it is one way to distract them at least for a while as they seek to restore operations.

The network is controlled by “Russian speaking criminals,” and the fear is that it will be used to disrupt the US election next month.

The effort is part of what Gen. Paul Nakasone, the head of Cyber Command, calls “persistent engagement,” or the imposition of cumulative costs on an adversary by keeping them constantly engaged. And that is a key feature of CyberCom’s activities to help protect the election against foreign threats, officials said.

Here’s General Nakasone talking about persistent engagement.

Microsoft is also disrupting Trickbot:

We disrupted Trickbot through a court order we obtained as well as technical action we executed in partnership with telecommunications providers around the world. We have now cut off key infrastructure so those operating Trickbot will no longer be able to initiate new infections or activate ransomware already dropped into computer systems.

[…]

We took today’s action after the United States District Court for the Eastern District of Virginia granted our request for a court order to halt Trickbot’s operations.

During the investigation that underpinned our case, we were able to identify operational details including the infrastructure Trickbot used to communicate with and control victim computers, the way infected computers talk with each other, and Trickbot’s mechanisms to evade detection and attempts to disrupt its operation. As we observed the infected computers connect to and receive instructions from command and control servers, we were able to identify the precise IP addresses of those servers. With this evidence, the court granted approval for Microsoft and our partners to disable the IP addresses, render the content stored on the command and control servers inaccessible, suspend all services to the botnet operators, and block any effort by the Trickbot operators to purchase or lease additional servers.

To execute this action, Microsoft formed an international group of industry and telecommunications providers. Our Digital Crimes Unit (DCU) led investigation efforts including detection, analysis, telemetry, and reverse engineering, with additional data and insights to strengthen our legal case from a global network of partners including FS-ISAC, ESET, Lumen’s Black Lotus Labs, NTT and Symantec, a division of Broadcom, in addition to our Microsoft Defender team. Further action to remediate victims will be supported by internet service providers (ISPs) and computer emergency readiness teams (CERTs) around the world.

This action also represents a new legal approach that our DCU is using for the first time. Our case includes copyright claims against Trickbot’s malicious use of our software code. This approach is an important development in our efforts to stop the spread of malware, allowing us to take civil action to protect customers in the large number of countries around the world that have these laws in place.

Brian Krebs comments:

In legal filings, Microsoft argued that Trickbot irreparably harms the company “by damaging its reputation, brands, and customer goodwill. Defendants physically alter and corrupt Microsoft products such as the Microsoft Windows products. Once infected, altered and controlled by Trickbot, the Windows operating system ceases to operate normally and becomes tools for Defendants to conduct their theft.”

This is a novel use of trademark law.

Google Responds to Warrants for “About” Searches

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/google-responds-to-warrants-for-about-searches.html

One of the things we learned from the Snowden documents is that the NSA conducts “about” searches. That is, searches based on activities and not identifiers. A normal search would be on a name, or IP address, or phone number. An about search would something like “show me anyone that has used this particular name in a communications,” or “show me anyone who was at this particular location within this time frame.” These searches are legal when conducted for the purpose of foreign surveillance, but the worry about using them domestically is that they are unconstitutionally broad. After all, the only way to know who said a particular name is to know what everyone said, and the only way to know who was at a particular location is to know where everyone was. The very nature of these searches requires mass surveillance.

The FBI does not conduct mass surveillance. But many US corporations do, as a normal part of their business model. And the FBI uses that surveillance infrastructure to conduct its own about searches. Here’s an arson case where the FBI asked Google who searched for a particular street address:

Homeland Security special agent Sylvette Reynoso testified that her team began by asking Google to produce a list of public IP addresses used to google the home of the victim in the run-up to the arson. The Chocolate Factory [Google] complied with the warrant, and gave the investigators the list. As Reynoso put it:

On June 15, 2020, the Honorable Ramon E. Reyes, Jr., United States Magistrate Judge for the Eastern District of New York, authorized a search warrant to Google for users who had searched the address of the Residence close in time to the arson.

The records indicated two IPv6 addresses had been used to search for the address three times: one the day before the SUV was set on fire, and the other two about an hour before the attack. The IPv6 addresses were traced to Verizon Wireless, which told the investigators that the addresses were in use by an account belonging to Williams.

Google’s response is that this is rare:

While word of these sort of requests for the identities of people making specific searches will raise the eyebrows of privacy-conscious users, Google told The Register the warrants are a very rare occurrence, and its team fights overly broad or vague requests.

“We vigorously protect the privacy of our users while supporting the important work of law enforcement,” Google’s director of law enforcement and information security Richard Salgado told us. “We require a warrant and push to narrow the scope of these particular demands when overly broad, including by objecting in court when appropriate.

“These data demands represent less than one per cent of total warrants and a small fraction of the overall legal demands for user data that we currently receive.”

Here’s another example of what seems to be about data leading to a false arrest.

According to the lawsuit, police investigating the murder knew months before they arrested Molina that the location data obtained from Google often showed him in two places at once, and that he was not the only person who drove the Honda registered under his name.

Avondale police knew almost two months before they arrested Molina that another man ­ his stepfather ­ sometimes drove Molina’s white Honda. On October 25, 2018, police obtained records showing that Molina’s Honda had been impounded earlier that year after Molina’s stepfather was caught driving the car without a license.

Data obtained by Avondale police from Google did show that a device logged into Molina’s Google account was in the area at the time of Knight’s murder. Yet on a different date, the location data from Google also showed that Molina was at a retirement community in Scottsdale (where his mother worked) while debit card records showed that Molina had made a purchase at a Walmart across town at the exact same time.

Molina’s attorneys argue that this and other instances like it should have made it clear to Avondale police that Google’s account-location data is not always reliable in determining the actual location of a person.

“About” searches might be rare, but that doesn’t make them a good idea. We have knowingly and willingly built the architecture of a police state, just so companies can show us ads. (And it is increasingly apparent that the advertising-supported Internet is heading for a crash.)

Analyze and improve email campaigns with Amazon Simple Email Service and Amazon QuickSight

Post Syndicated from Apoorv Gakhar original https://aws.amazon.com/blogs/messaging-and-targeting/analyze-and-improve-email-campaigns-with-amazon-simple-email-service-and-amazon-quicksight/

Email is a popular channel for applications, used in both marketing campaigns and other outbound customer communications. The challenge with email is that it can become increasingly complex to manage for companies that must send large quantities of messages per month. This complexity is especially true when companies need to measure detailed email engagement metrics to track campaign success.

As a marketer, you want to monitor several metrics, including open rates, click-through rates, bounce rates, and delivery rates. If you do not track your email results, you could potentially be wasting your campaign resources. Monitoring and interpreting your sending results can help you deliver the best content possible to your subscribers’ inboxes, and it can also ensure that your IP reputation stays high. Mailbox providers prioritize inbox placement for senders that deliver relevant content. As a business professional, tracking your emails can also help you stay on top of hot leads and important clients. For example, if someone has opened your email multiple times in one day, it might be a good idea to send out another follow-up email to touch base.

Building a large-scale email solution is a complex and expensive challenge for any business. You would need to build infrastructure, assemble your network, and warm up your IP addresses. Alternatively, working with some third-party email solutions require contract negotiations and upfront costs.

Fortunately, Amazon Simple Email Service (SES) has a highly scalable and reliable backend infrastructure to reduce the preceding challenges. It has improved content filtering techniques, reputation management features, and a vast array of analytics and reporting functions. These features help email senders reach their audiences and make it easier to manage email channels across applications. Amazon SES also provides API operations to monitor your sending activities through simple API calls. You can publish these events to Amazon CloudWatch, Amazon Kinesis Data Firehose, or by using Amazon Simple Notification Service (SNS).

In this post, you learn how to build and automate a serverless architecture that analyzes email events. We explore how to track important metrics such as open and click rate of the emails.

Solution overview


The metrics that you can measure using Amazon SES are referred to as email sending events. You can use Amazon CloudWatch to retrieve Amazon SES event data. You can also use Amazon SNS to interpret Amazon SES event data. However, in this post, we are going to use Amazon Kinesis Data Firehose to monitor our user sending activity.

Enable Amazon SES configuration sets with open and click metrics and publish email sending events to Amazon Kinesis Data Firehose as JSON records. A Lambda function is used to parse the JSON records and publish the content in the Amazon S3 bucket.

Ingested data lands in an Amazon S3 bucket that we refer to as the raw zone. To make that data available, you have to catalog its schema in the AWS Glue data catalog. You create and run the AWS Glue crawler that crawls your data sources and construct your Data Catalog. The Data Catalog uses pre-built classifiers for many popular source formats and data types, including JSON, CSV, and Parquet.

When the crawler is finished creating the table definition and schema, you analyze the data using Amazon Athena. It is an interactive query service that makes it easy to analyze data in Amazon S3 using SQL. Point to your data in Amazon S3, define the schema, and start querying using standard SQL, with most results delivered in seconds.

Now you can build visualizations, perform ad hoc analysis, and quickly get business insights from the Amazon SES event data using Amazon QuickSight. You can easily run SQL queries using Amazon Athena on data stored in Amazon S3, and build business dashboards within Amazon QuickSight.


Deploying the architecture:

Configuring Amazon Kinesis Data Firehose to write to Amazon S3:

  1. Navigate to the Amazon Kinesis in the AWS Management Console. Choose Kinesis Data Firehose and create a delivery stream.
  2. Enter delivery stream name as “SES_Firehose_Demo”.
  3. Under the source category, select “Direct Put or other sources”.
  4. On the next page, make sure to enable Data Transformation of source records with AWS Lambda. We use AWS Lambda to parse the notification contents that we only process the required information as per the use case.
  5. Click the “Create New” Lambda function.
  6. Click on “General Kinesis Data FirehoseProcessing” Lambda blueprint and this opens up the Lambda console. Enter following values in Lambda
    • Name: SES-Firehose-Json-Parser
    • Execution role: Create a new role with basic Lambda permissions.
  7. Click “Create Function”. Now replace the Lambda code with the following provided code and save the function.
    • 'use strict';
      console.log('Loading function');
      exports.handler = (event, context, callback) => {
         /* Process the list of records and transform them */
          const output = event.records.map((record) => {
              console.log(record.recordId);
              const payload =JSON.parse((Buffer.from(record.data, 'base64').toString()))
              console.log("payload : " + payload);
              
              if (payload.eventType == "Click") {
              const resultPayLoadClick = {
                      eventType : payload.eventType,
                      destinationEmailId : payload.mail.destination[0],
                      sourceIp : payload.click.ipAddress,
                  };
              console.log("resultPayLoad : " + resultPayLoadClick.eventType + resultPayLoadClick.destinationEmailId + resultPayLoadClick.sourceIp);
              
              //const parsed = resultPayLoad[0];
              //console.log("parsed : " + (Buffer.from(JSON.stringify(resultPayLoad))).toString('base64'));
              
              
              return{
                  recordId: record.recordId,
                  result: 'Ok',
                  data: (Buffer.from(JSON.stringify(resultPayLoadClick))).toString('base64'),
              };
              }
              else {
                  const resultPayLoadOpen = {
                      eventType : payload.eventType,
                      destinationEmailId : payload.mail.destination[0],
                      sourceIp : payload.open.ipAddress,
                  };
              console.log("resultPayLoad : " + resultPayLoadOpen.eventType + resultPayLoadOpen.destinationEmailId + resultPayLoadOpen.sourceIp);
              
              //const parsed = resultPayLoad[0];
              //console.log("parsed : " + (Buffer.from(JSON.stringify(resultPayLoad))).toString('base64'));
              
              
              return{
                  recordId: record.recordId,
                  result: 'Ok',
                  data: (Buffer.from(JSON.stringify(resultPayLoadOpen))).toString('base64'),
              };
              }
          });
          console.log("Output : " + output.data);
          console.log(`Processing completed.  Successful records ${output.length}.`);
          callback(null, { records: output });
      };

      Please note:

      For this blog, we are only filtering out three fields i.e. Eventname, destination_Email, and SourceIP. If you want to store other parameters you can modify your code accordingly. For the list of information that we receive in notifications, you may check out the following document.

      https://docs.aws.amazon.com/ses/latest/DeveloperGuide/event-publishing-retrieving-firehose-examples.html

  8. Now, navigate back to your Amazon Kinesis Data Firehose console and choose the newly created Lambda function.
  9. Keep the convert record format disabled and click “Next”.
  10. In the destination, choose Amazon S3 and select a target Amazon S3 bucket. Create a new bucket if you do not want to use the existing bucket.
  11. Enter the following values for Amazon S3 Prefix and Error Prefix. When event data is published.
    • Prefix:
      fhbase/year=!{timestamp:yyyy}/month=!{timestamp:MM}/day=!{timestamp:dd}/hour=!{timestamp:HH}/
    • Error Prefix:
      fherroroutputbase/!{firehose:random-string}/!{firehose:error-output-type}/!{timestamp:yyyy/MM/dd}/
  12. You may utilize the above values in the Amazon S3 prefix and error prefix. If you use your own prefixes make sure to accordingly update the target values in AWS Glue which you will see in further process.
  13. Keep the Amazon S3 backup option disabled and click “Next”.
  14. On the next page, under the Permissions section, select create a new role. This opens up a new tab and then click “Allow” to create the role.
  15. Navigate back to the Amazon Kinesis Data Firehose console and click “Next”.
  16. Review the changes and click on “Create delivery stream”.

Configure Amazon SES to publish event data to Kinesis Data Firehose:

  1. Navigate to Amazon SES console and select “Email Addresses” from the left side.
  2. Click on “Verify a New Email Address” on the top. Enter your email address to which you send a test email.
  3. Go to your email inbox and click on the verify link. Navigate back to the Amazon SES console and you will see verified status on the email address provided.
  4. Open the Amazon SES console and select Configuration set from the left side.
  5. Create a new configuration set. Enter “SES_Firehose_Demo”  as the configuration set name and click “Create”.
  6. Choose Kinesis Data Firehose as the destination and provide the following details.
    • Name: OpenClick
    • Event Types: Open and Click
  7. In the IAM Role field, select ‘Let SES make a new role’. This allows SES to create a new role and add sufficient permissions for this use case in that role.
  8. Click “Save”.

Sending a Test email:

  1. Navigate to Amazon SES console, click on “Email Addresses” on the left side.
  2. Select your verified email address and click on “Send a Test email”.
  3. Make sure you select the raw email format. You may use the following format to send out a test email from the console. Make sure you send out this email to a recipient inbox to which you have the access.
    • X-SES-CONFIGURATION-SET: SES_Firehose_Demo
      X-SES-MESSAGE-TAGS: Email=NULL
      From: [email protected]
      To: [email protected]
      Subject: Test email
      Content-Type: multipart/alternative;
          		boundary="----=_boundary"
      
      ------=_boundary
      Content-Type: text/html; charset=UTF-8
      Content-Transfer-Encoding: 7bit
      This is a test email.
      
      <a href="https://aws.amazon.com/">Amazon Web Services</a>
      ------=_boundary
  4. Once the email is received in the recipient’s inbox, open the email and click the link present in the same. This generates a click and open event and send the response back to SES.

Creating Glue Crawler:

  1. Navigate to the AWS Glue console, select “crawler” from the left side, and then click on “Add crawler” on the top.
  2. Enter the crawler name as “SES_Firehose_Crawler” and click “Next”.
  3. Under Crawler source type, select “Data stores” and click “Next”.
  4. Select Amazon S3 as the data source and prove the required path. Include the path until the “fhbase” folder.
  5. Select “no” under Add another data source section.
  6. In the IAM role, select the option to ‘Create an IAM role’. Enter the name as “SES_Firehose-Crawler”. This provides the necessary permissions automatically to the newly created role.
  7. In the frequency section, select run on demand and click “Next”. You may choose this value as per your use case.
  8. Click on add Database and provide the name as “ses_firehose_glue_db”. Click on create and then click “Next”.
  9. Review your Glue crawler setting and click on “Finish”.
  10. Run the above-created crawler. This crawls the data from the specified Amazon S3 bucket and create a catalog and table definition.
  11. Now navigate to “tables” on the left, and verify a “fhbase” table is created after you run the crawler.

If you want to analyze the data stored until now, you can use Amazon Athena and test the queries. If not, you can move to the Amazon Quicksight directly.

Analyzing the data using Amazon Athena:

  1. Open Athena console and select the database, which is created using AWS Glue
  2. Click on “setup a query result location in Amazon S3” as shown in the following screenshot.
  3. Navigate to the Amazon S3 bucket created in earlier steps and create a folder called “AthenaQueryResult”. We store our Athena query result in this bucket.
  4. Now navigate back to Amazon Athena and select the Amazon S3 bucket with the folder location as shown in the following screenshot and click “Save”.
  5. Run the following query to test the sample output and accordingly modify your SQL query to get the desired output.
    • Select * from “ses_firehose_glue_db”.”fhbase”

Note: If you want to track the opened emails by unique Ip addresses then you can modify your SQL query accordingly. This is because every time an email gets opened, you will receive a notification even if the same email was previously opened.


Visualizing the data in Amazon QuickSight dashboards:

  1. Now, let’s analyze this data using Amazon Athena via Amazon Quicksight.
  2. Log into Amazon Quicksight and choose Manage data, New dataset. Choose Amazon Athena as a new data source.
  3. Enter the data source name as “SES-Demo” and click on “Create the data source”.
  4. Select your database from the drop-down as “ses_firehose_glue_db” and table “fhbase” that you have created in AWS Glue.
  5. And add a custom SQL based on your use case and click on “Confirm query”. Refer to the example below.
  6. You can perform ad hoc analysis and modify your query according to your business needs as shown in the following image. Click “Save & Visualize”.
  7. You can now visualize your event data on Amazon Quicksight dashboard. You can use various graphs to represent your data. For this demo, the default graph is used and two fields are selected to populate on the graph, as shown below.


Conclusion:

This architecture shows how to track your email sending activity at a granular level. You set up Amazon SES to publish event data to Amazon Kinesis Data Firehose based on fine-grained email characteristics that you define. You can also track several types of email sending events, including sends, deliveries, bounces, complaints, rejections, rendering failures, and delivery delays. This information can be useful for operational and analytical purposes.

To get started with Amazon SES, follow this quick start guide and you can learn more about monitoring sending activity here.

About the Authors

Chirag Oswal is a solutions architect and AR/VR specialist working with the public sector India. He works with AWS customers to help them adopt the cloud operating model on a large scale.

Apoorv Gakhar is a Cloud Support Engineer and an Amazon SES Expert. He is working with AWS to help the customers integrate their applications with various AWS Services.


Additional Resources:

Amazon SES Dedicated IP Pools

Amazon Personalize optimizer using Amazon Pinpoint events

Template Personalization using Amazon Pinpoint


Hacking Apple for Profit

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/10/hacking-apple-for-profit.html

Five researchers hacked Apple Computer’s networks — not their products — and found fifty-five vulnerabilities. So far, they have received $289K.

One of the worst of all the bugs they found would have allowed criminals to create a worm that would automatically steal all the photos, videos, and documents from someone’s iCloud account and then do the same to the victim’s contacts.

Lots of details in this blog post by one of the hackers.

AI-Man: a handy guide to video game artificial intelligence

Post Syndicated from Ryan Lambie original https://www.raspberrypi.org/blog/ai-man-a-handy-guide-to-video-game-artificial-intelligence/

Discover how non-player characters make decisions by tinkering with this Unity-based Pac-Man homage. Paul Roberts wrote this for the latest issue of Wireframe magazine.

From the first video game to the present, artificial intelligence has been a vital part of the medium. While most early games had enemies that simply walked left and right, like the Goombas in Super Mario Bros., there were also games like Pac-Man, where each ghost appeared to move intelligently. But from a programming perspective, how do we handle all the different possible states we want our characters to display?

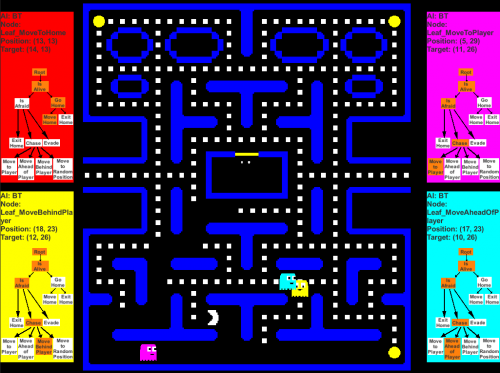
Here’s AI-Man, our homage to a certain Namco maze game. You can switch between AI types to see how they affect the ghosts’ behaviours.

For example, how do we control whether a ghost is chasing Pac-Man, or running away, or even returning to their home? To explore these behaviours, we’ll be tinkering with AI-Man – a Pac-Man-style game developed in Unity. It will show you how the approaches discussed in this article are implemented, and there’s code available for you to modify and add to. You can freely download the AI-Man project here. One solution to managing the different states a character can be in, which has been used for decades, is a finite state machine, or FSM for short. It’s an approach that describes the high-level actions of an agent, and takes its name simply from the fact that there are a finite number of states from which to transition between, with each state only ever doing one thing.

Altered states

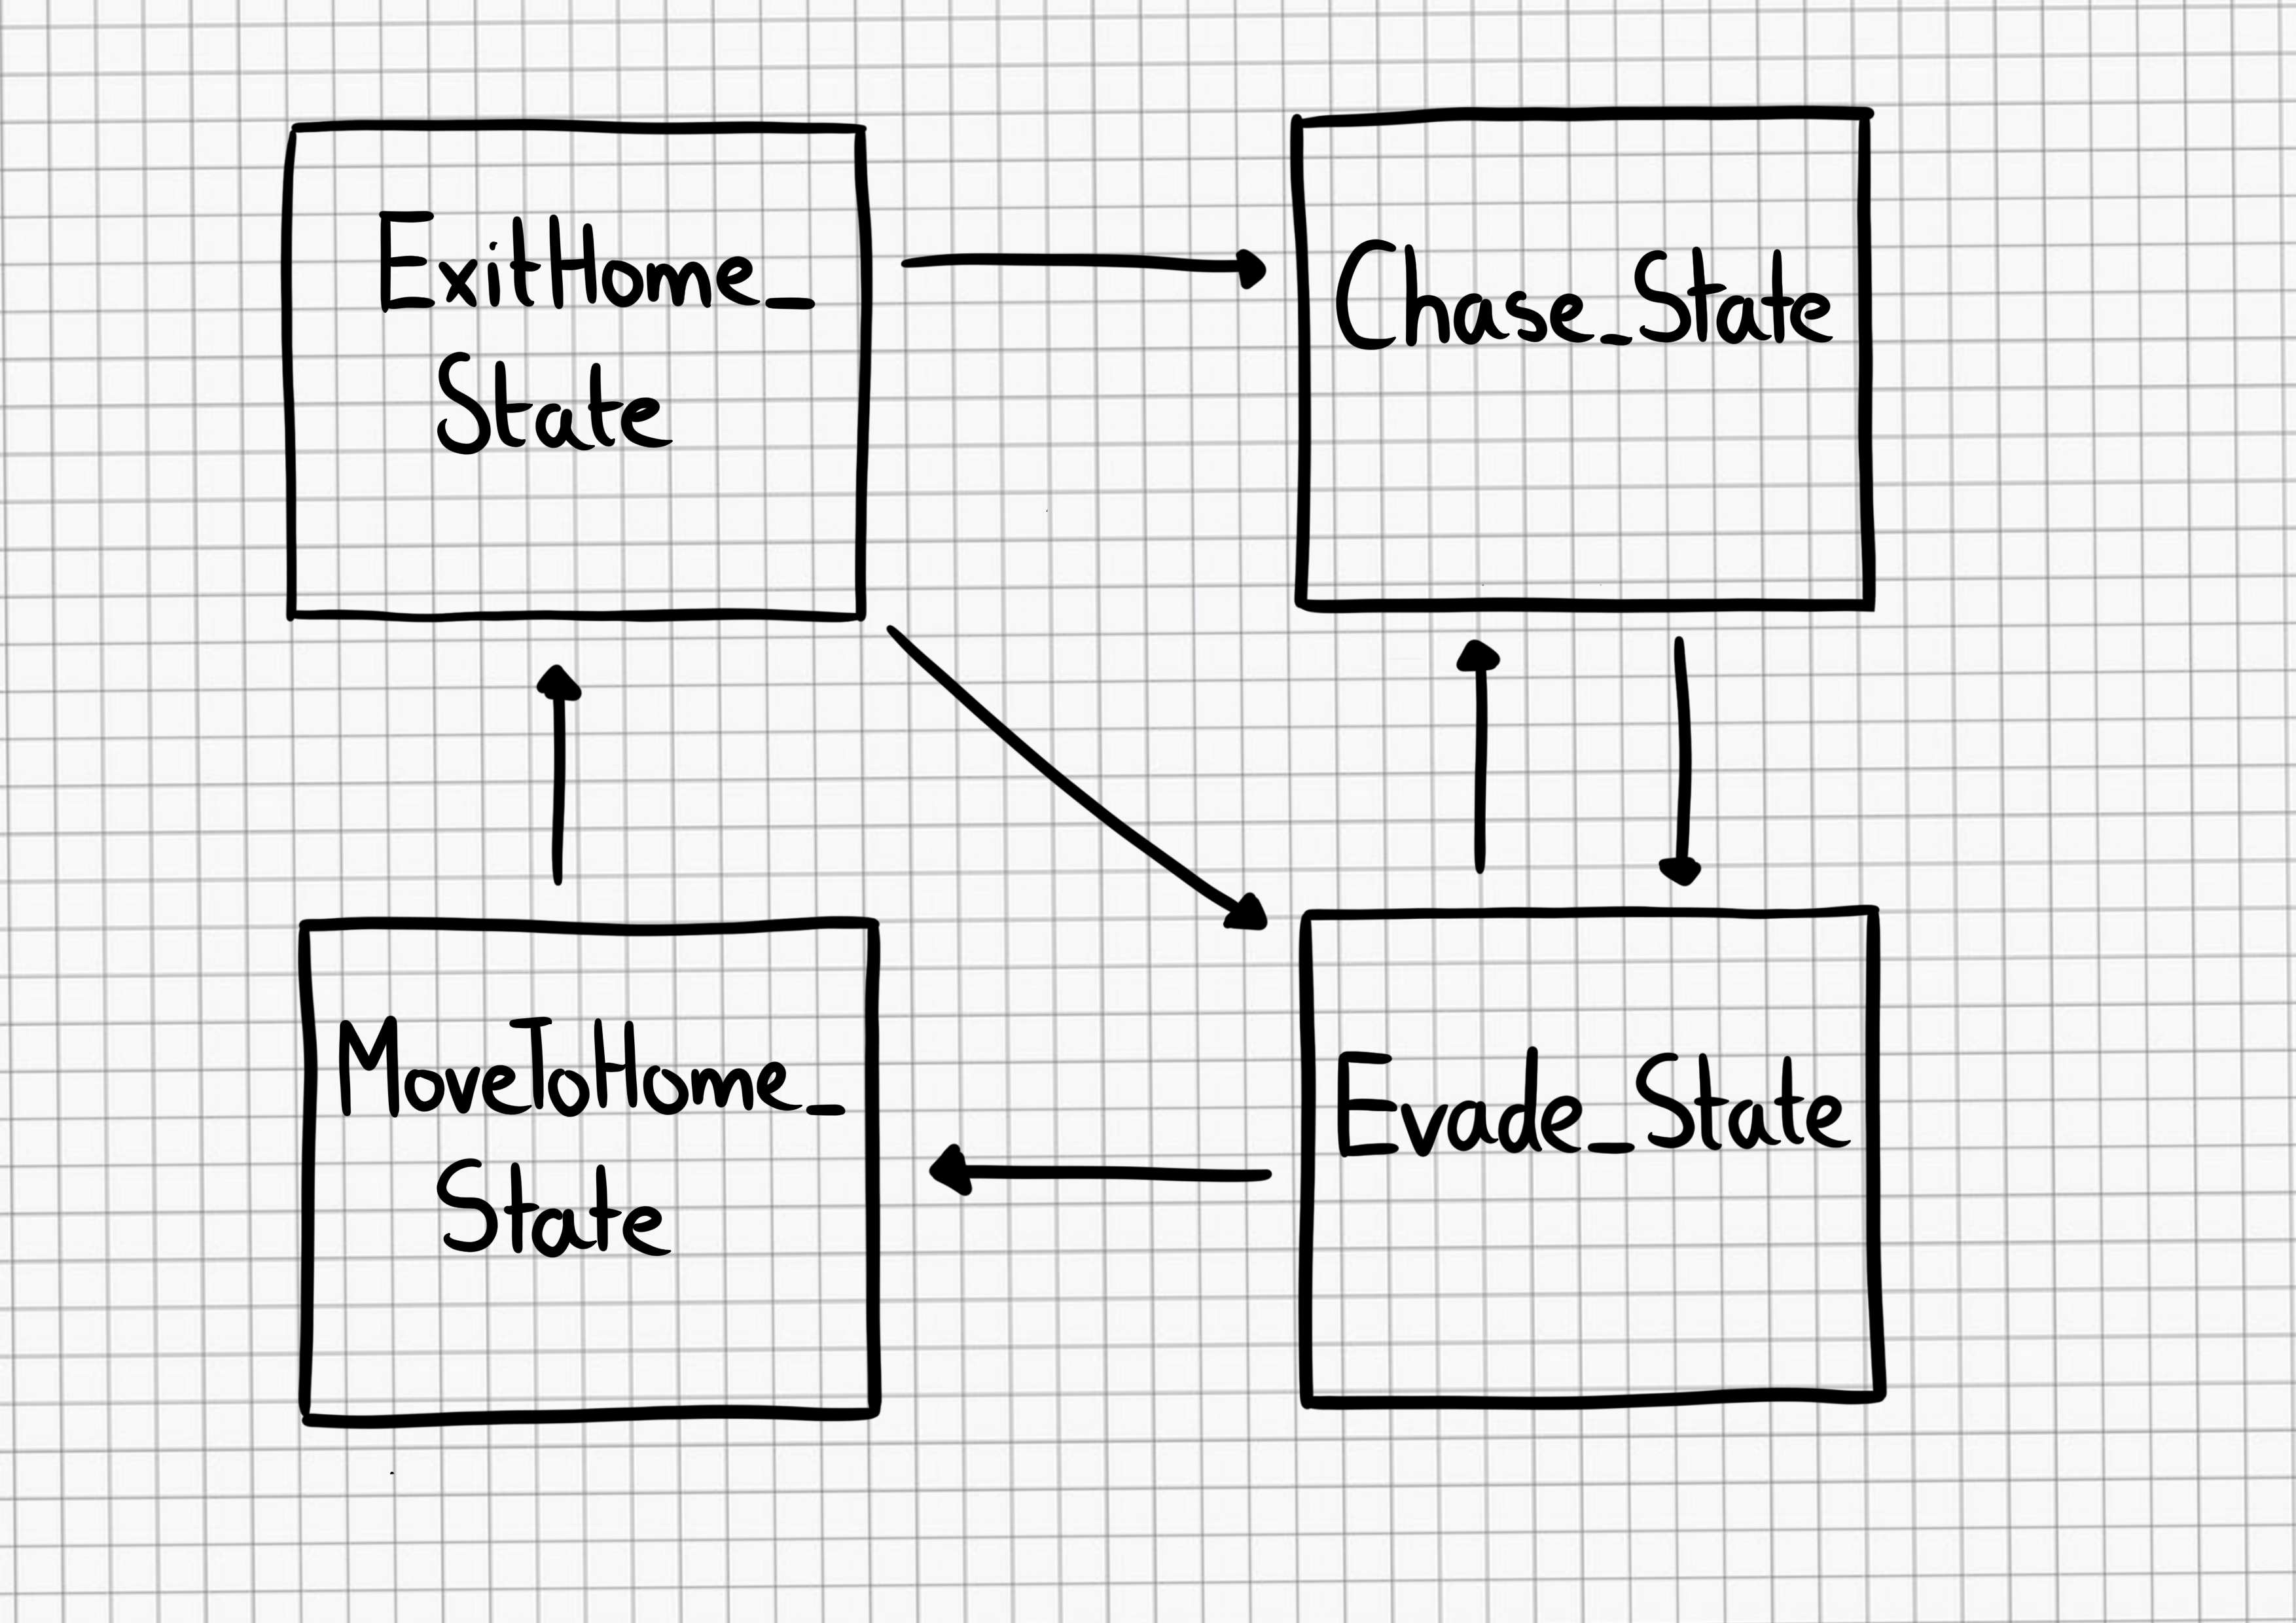
To explain what’s meant by high level, let’s take a closer look at the ghosts in Pac-Man. The highlevel state of a ghost is to ‘Chase’ Pac-Man, but the low level is how the ghost actually does this. In Pac-Man, each ghost has its own behaviour in which it hunts the player down, but they’re all in the same high-level state of ‘Chase’. Looking at Figure 1, you can see how the overall behaviour of a ghost can be depicted extremely easily, but there’s a lot of hidden complexity. At what point do we transition between states? What are the conditions on moving between states across the connecting lines? Once we have this information, the diagram can be turned into code with relative ease. You could use simple switch statements to achieve this, or we could achieve the same using an object-oriented approach.

Figure 1: A finite state machine

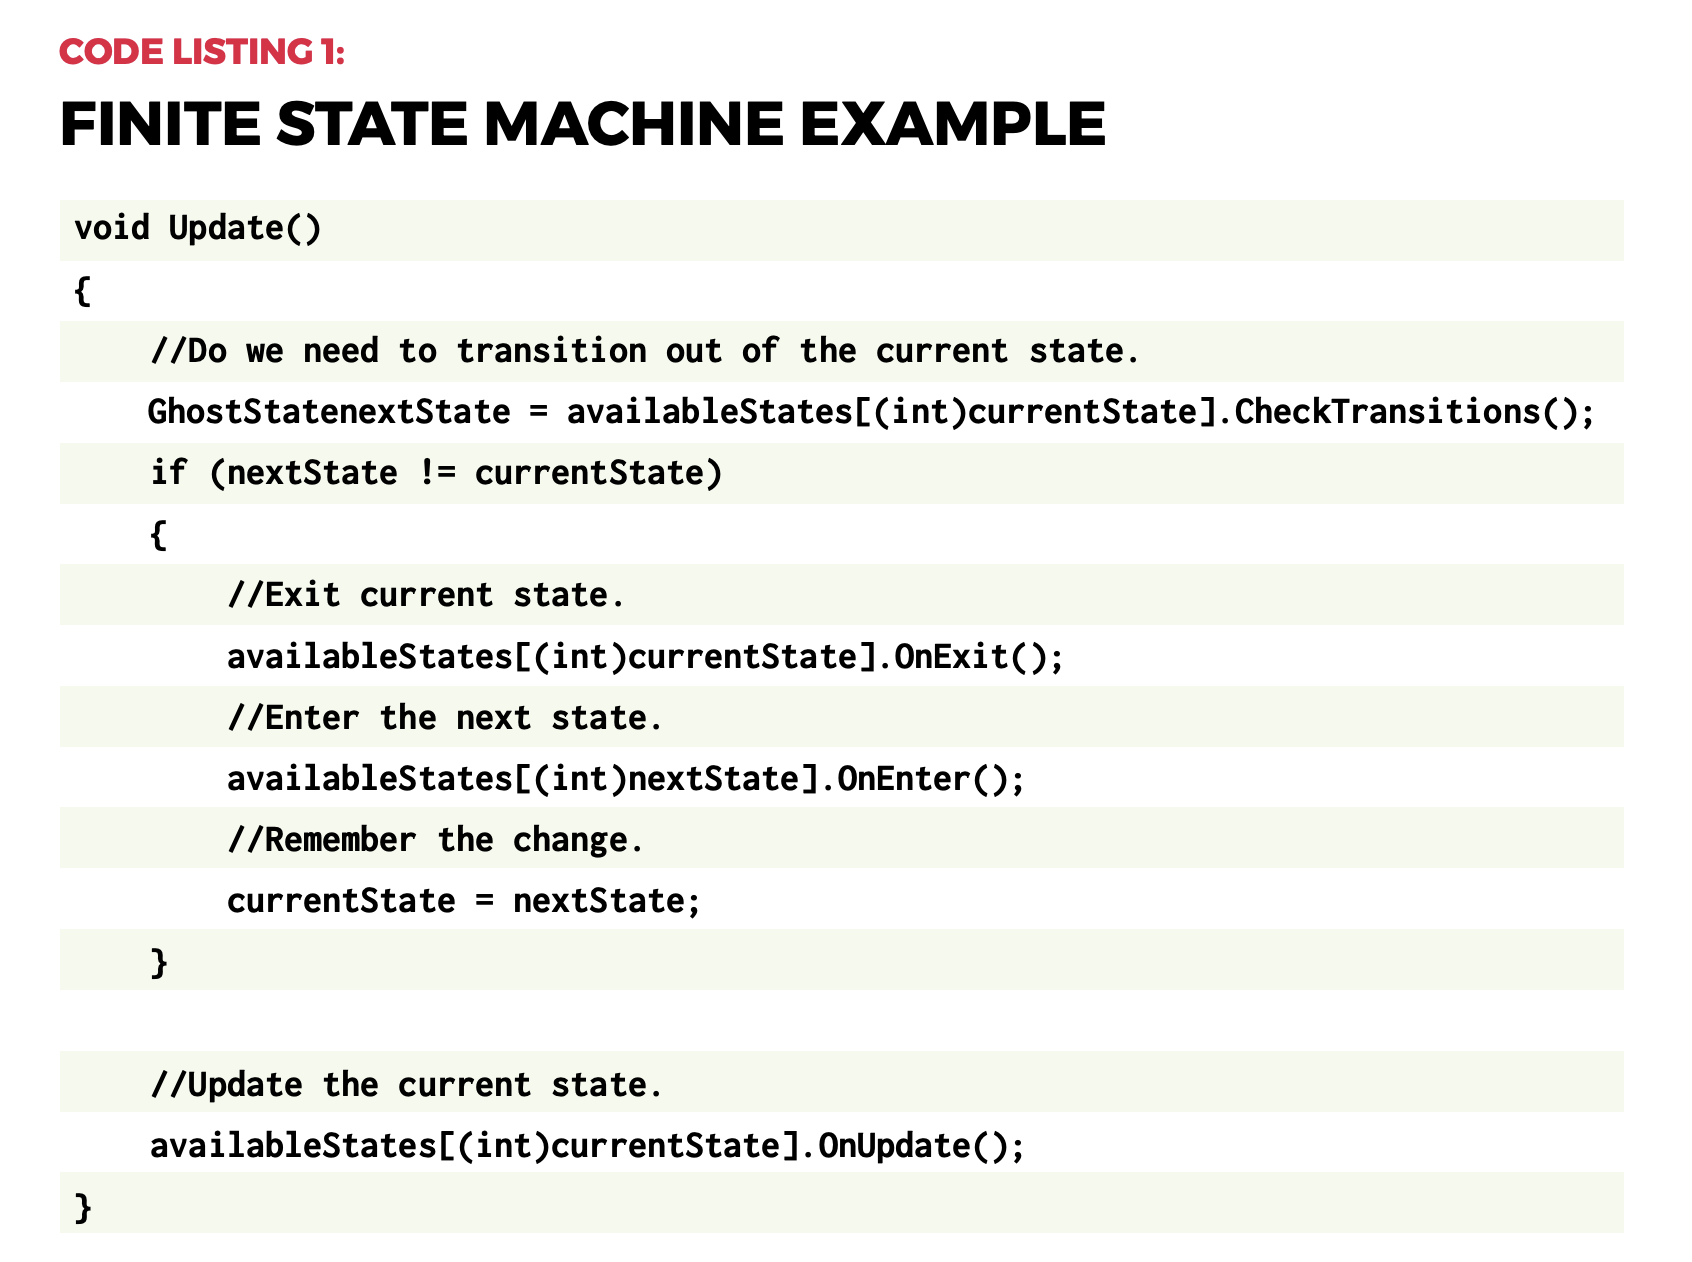
Using switch statements can quickly become cumbersome the more states we add, so I’ve used the object-oriented approach in the accompanying project, and an example code snippet can be seen in Code Listing 1. Each state handles whether it needs to transition into another state, and lets the state machine know. If a transition’s required, the Exit() function is called on the current state, before calling the Enter() function on the new state. This is done to ensure any setup or cleanup is done, after which the Update() function is called on whatever the current state is. The Update()function is where the low-level code for completing the state is processed. For a project as simple as Pac-Man, this only involves setting a different position for the ghost to move to.

Hidden complexity

Extending this approach, it’s reasonable for a state to call multiple states from within. This is called a hierarchical finite state machine, or HFSM for short. An example is an agent in Call of Duty: Strike Team being instructed to seek a stealthy position, so the high-level state is ‘Find Cover’, but within that, the agent needs to exit the dumpster he’s currently hiding in, find a safe location, calculate a safe path to that location, then repeatedly move between points on that path until he reaches the target position.

FSMs can appear somewhat predictable as the agent will always transition into the same state. This can be accommodated for by having multiple options that achieve the same goal. For example, when the ghosts in our Unity project are in the ‘Chase’ state, they can either move to the player, get in front of the player, or move to a position behind the player. There’s also an option to move to a random position. The FSM implemented has each ghost do one of these, whereas the behaviour tree allows all ghosts to switch between the options every ten seconds. A limitation of the FSM approach is that you can only ever be in a single state at a particular time. Imagine a tank battle game where multiple enemies can be engaged. Simply being in the ‘Retreat’ state doesn’t look smart if you’re about to run into the sights of another enemy. The worst-case scenario would be our tank transitions between ‘Attack’ and ‘Retreat’ states on each frame – an issue known as state thrashing – and gets stuck, and seemingly confused about what to do in this situation. What we need is away to be in multiple states at the same time: ideally retreating from tank A, whilst attacking tank B. This is where fuzzy finite state machines, or FFSM for short, come in useful.

This approach allows you to be in a particular state to a certain degree. For example, my tank could be 80% committed to the Retreat state (avoid tank A), and 20% committed to the Attack state (attack tank B). This allows us to both Retreat and Attack at the same time. To achieve this, on each update, your agent needs to check each possible state to determine its degree of commitment, and then call each of the active states’ updates. This differs from a standard FSM, where you can only ever be in a single state. FFSMs can be in none, one, two, or however many states you like at one time. This can prove tricky to balance, but it does offer an alternative to the standard approach.

No memory

Another potential issue with an FSM is that the agent has no memory of what they were previously doing. Granted, this may not be important: in the example given, the ghosts in Pac-Man don’t care about what they were doing, they only care about what they are doing, but in other games, memory can be extremely important. Imagine instructing a character to gather wood in a game like Age of Empires, and then the character gets into a fight. It would be extremely frustrating if the characters just stood around with nothing to do after the fight had concluded, and for the player to have to go back through all these characters and reinstruct them after the fight is over. It would be much better for the characters to return to their previous duties.

“FFSMs can be in one, none,

two, or however many states

you like.”

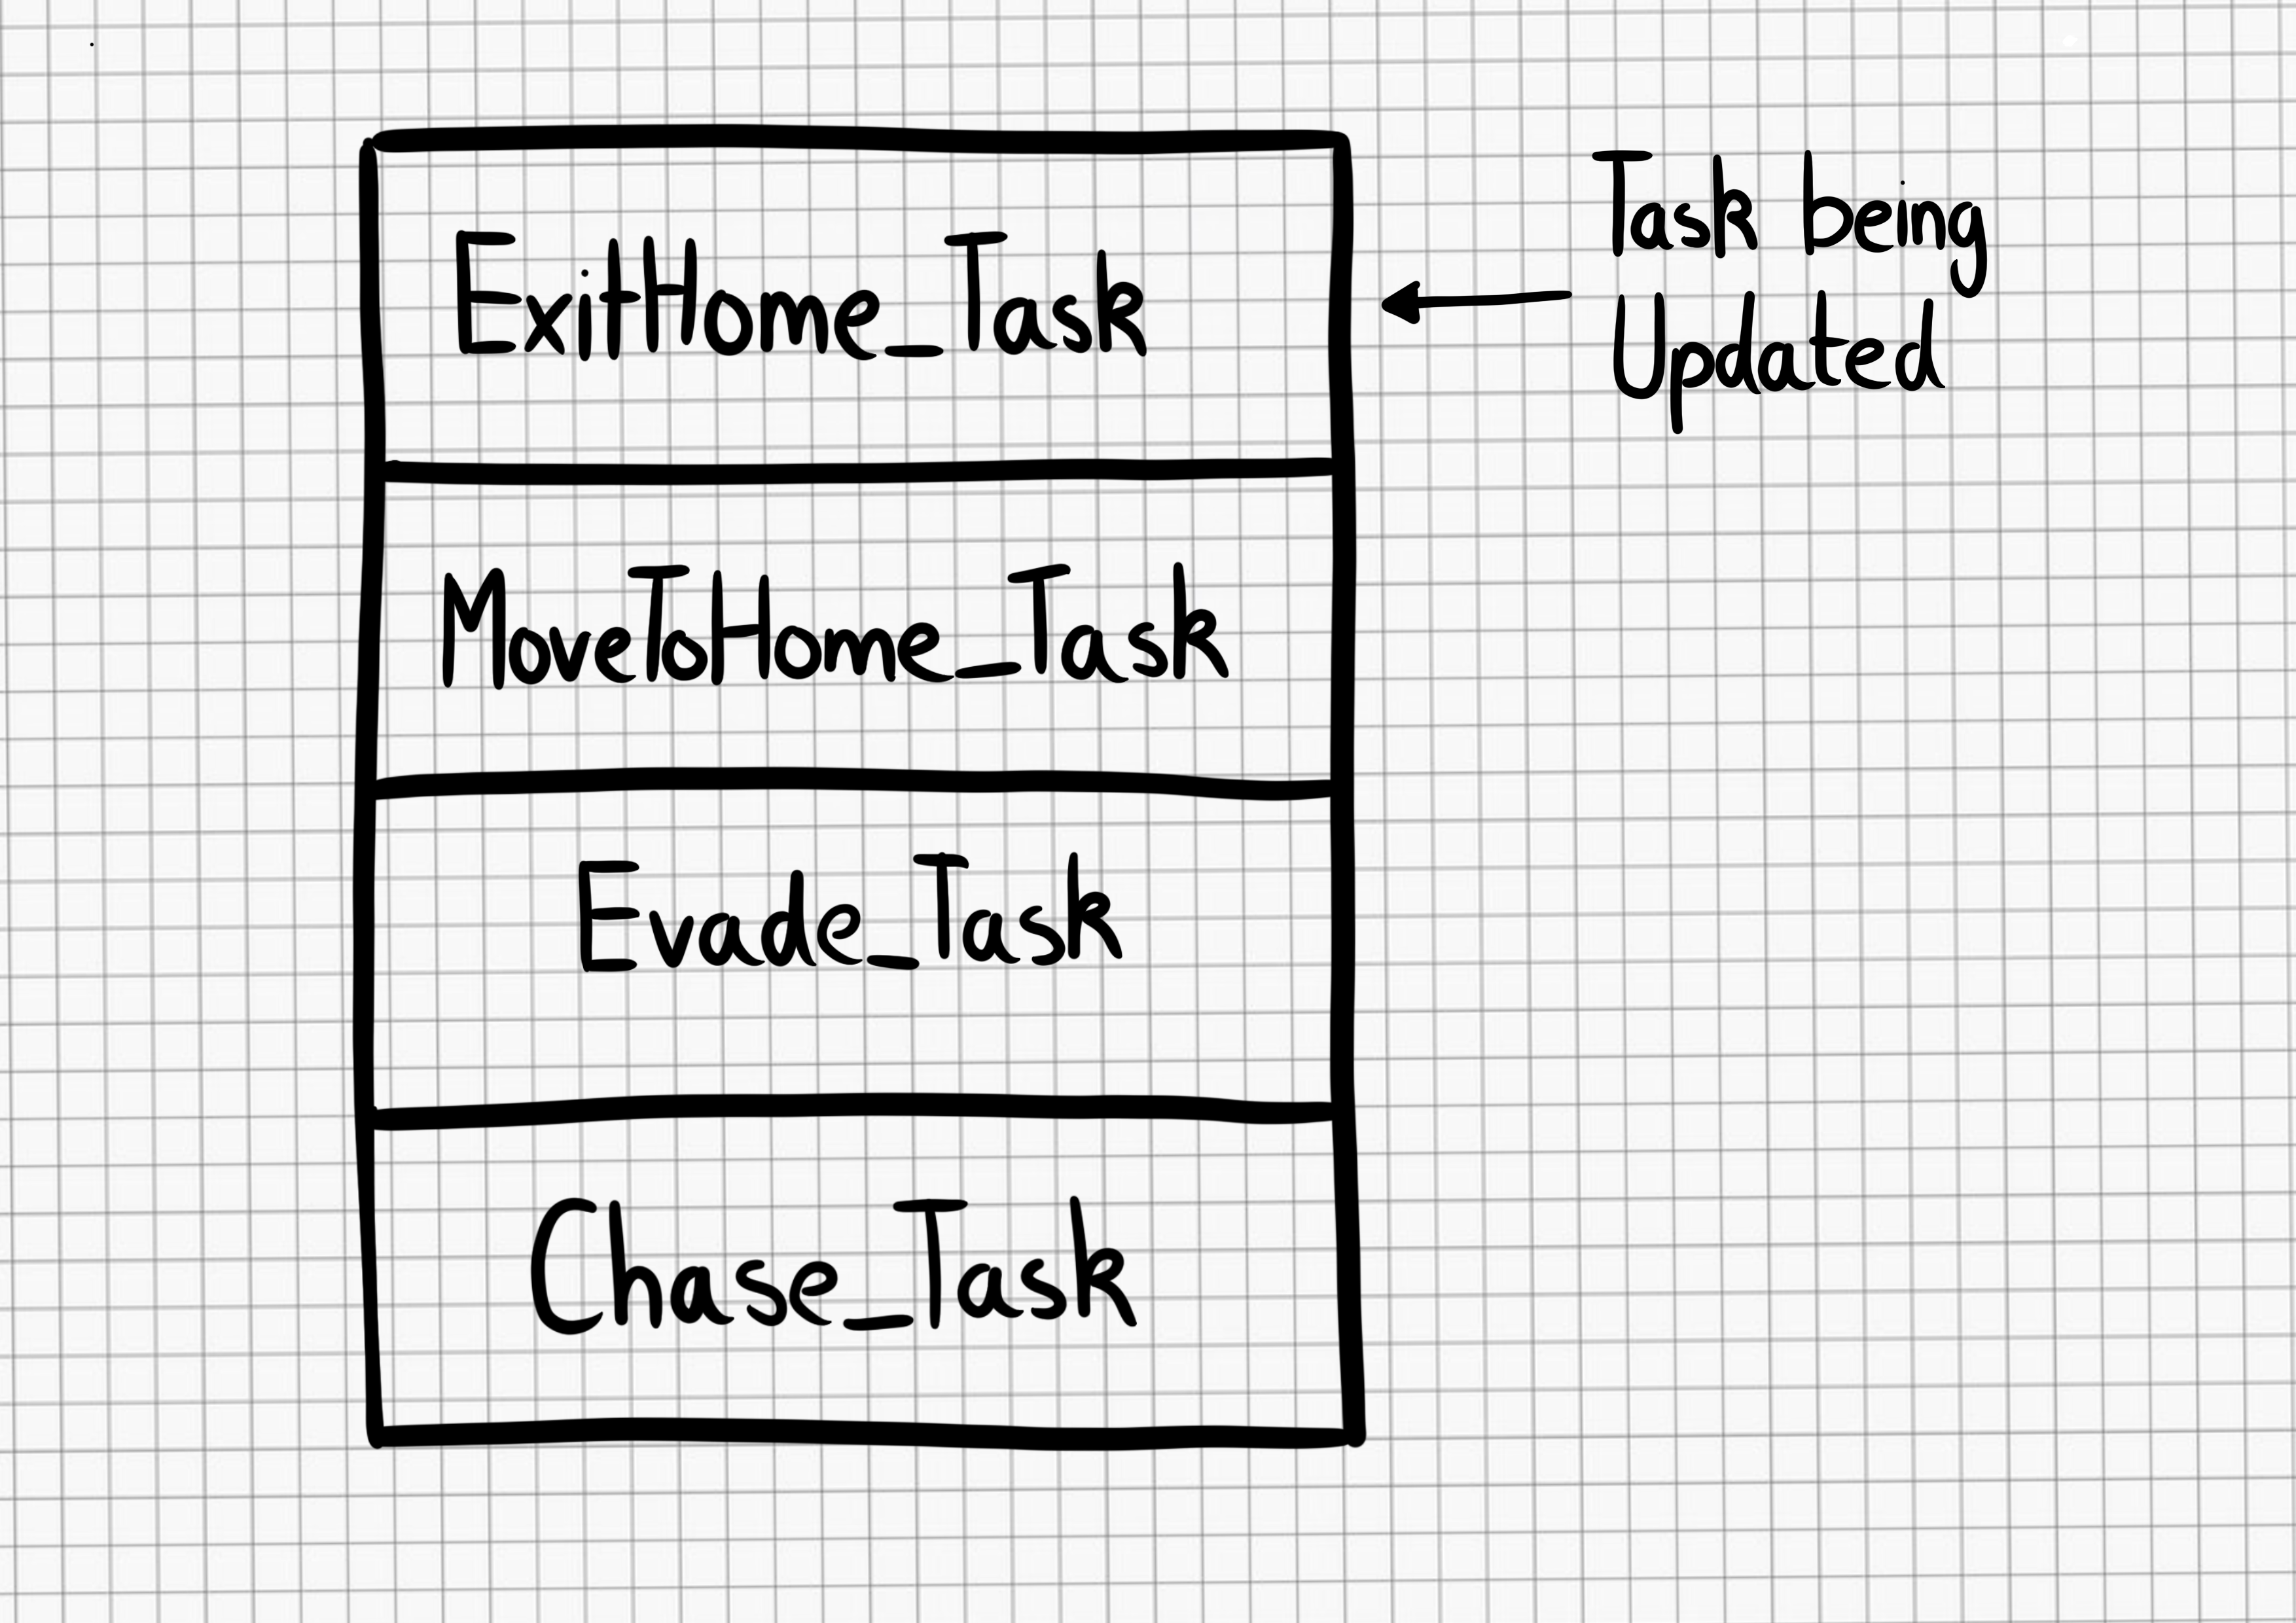
We can incorporate the idea of memory quite easily by using the stack data structure. The stack will hold AI states, with only the top-most element receiving the update. This in effect means that when a state is completed, it’s removed from the stack and the previous state is then processed. Figure 2 depicts how this was achieved in our Unity project. To differentiate the states from the FSM approach, I’ve called them tasks for the stackbased implementation. Looking at Figure 2, it shows how (from the bottom), the ghost was chasing the player, then the player collected a power pill, which resulted in the AI adding an Evade_Task – this now gets the update call, not the Chase_Task. While evading the player, the ghost was then eaten.

At this point, the ghost needed to return home, so the appropriate task was added. Once home, the ghost needed to exit this area, so again, the relevant task was added. At the point the ghost exited home, the ExitHome_Task was removed, which drops processing back to MoveToHome_Task. This was no longer required, so it was also removed. Back in the Evade_Task, if the power pill was still active, the ghost would return to avoiding the player, but if it had worn off, this task, in turn, got removed, putting the ghost back in its default task of Chase_Task, which will get the update calls until something else in the world changes.

Figure 2: Stack-based finite state machine.

Behaviour trees

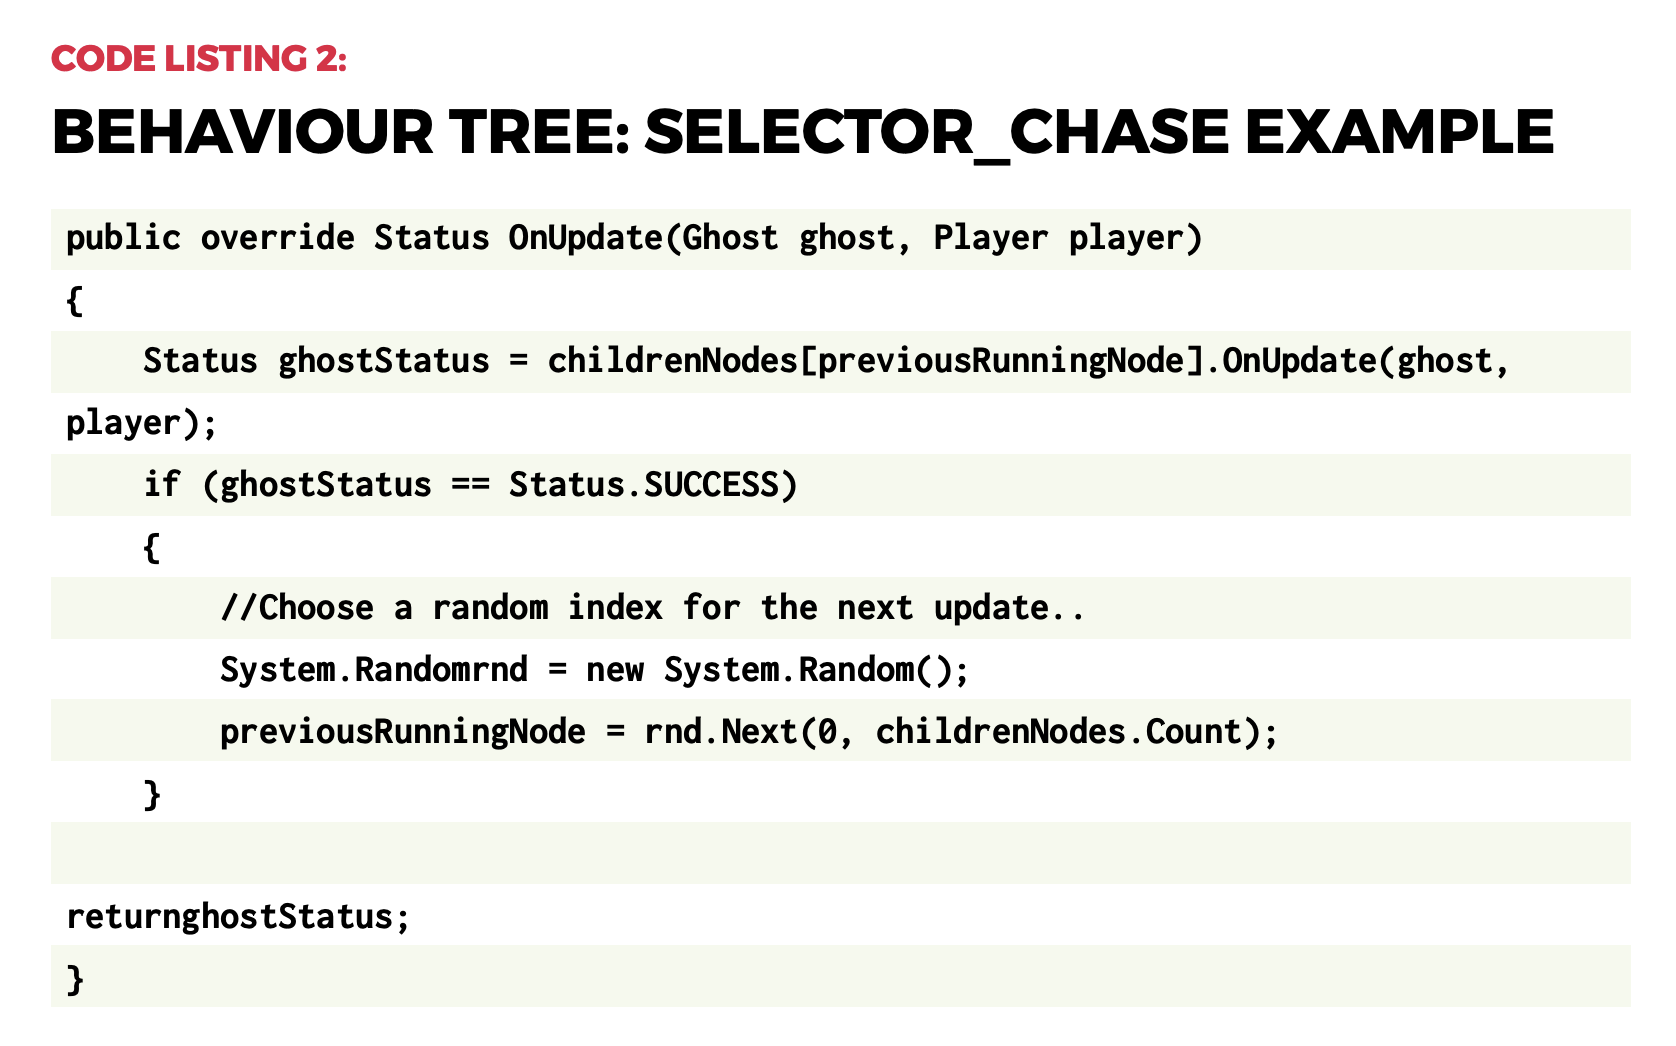
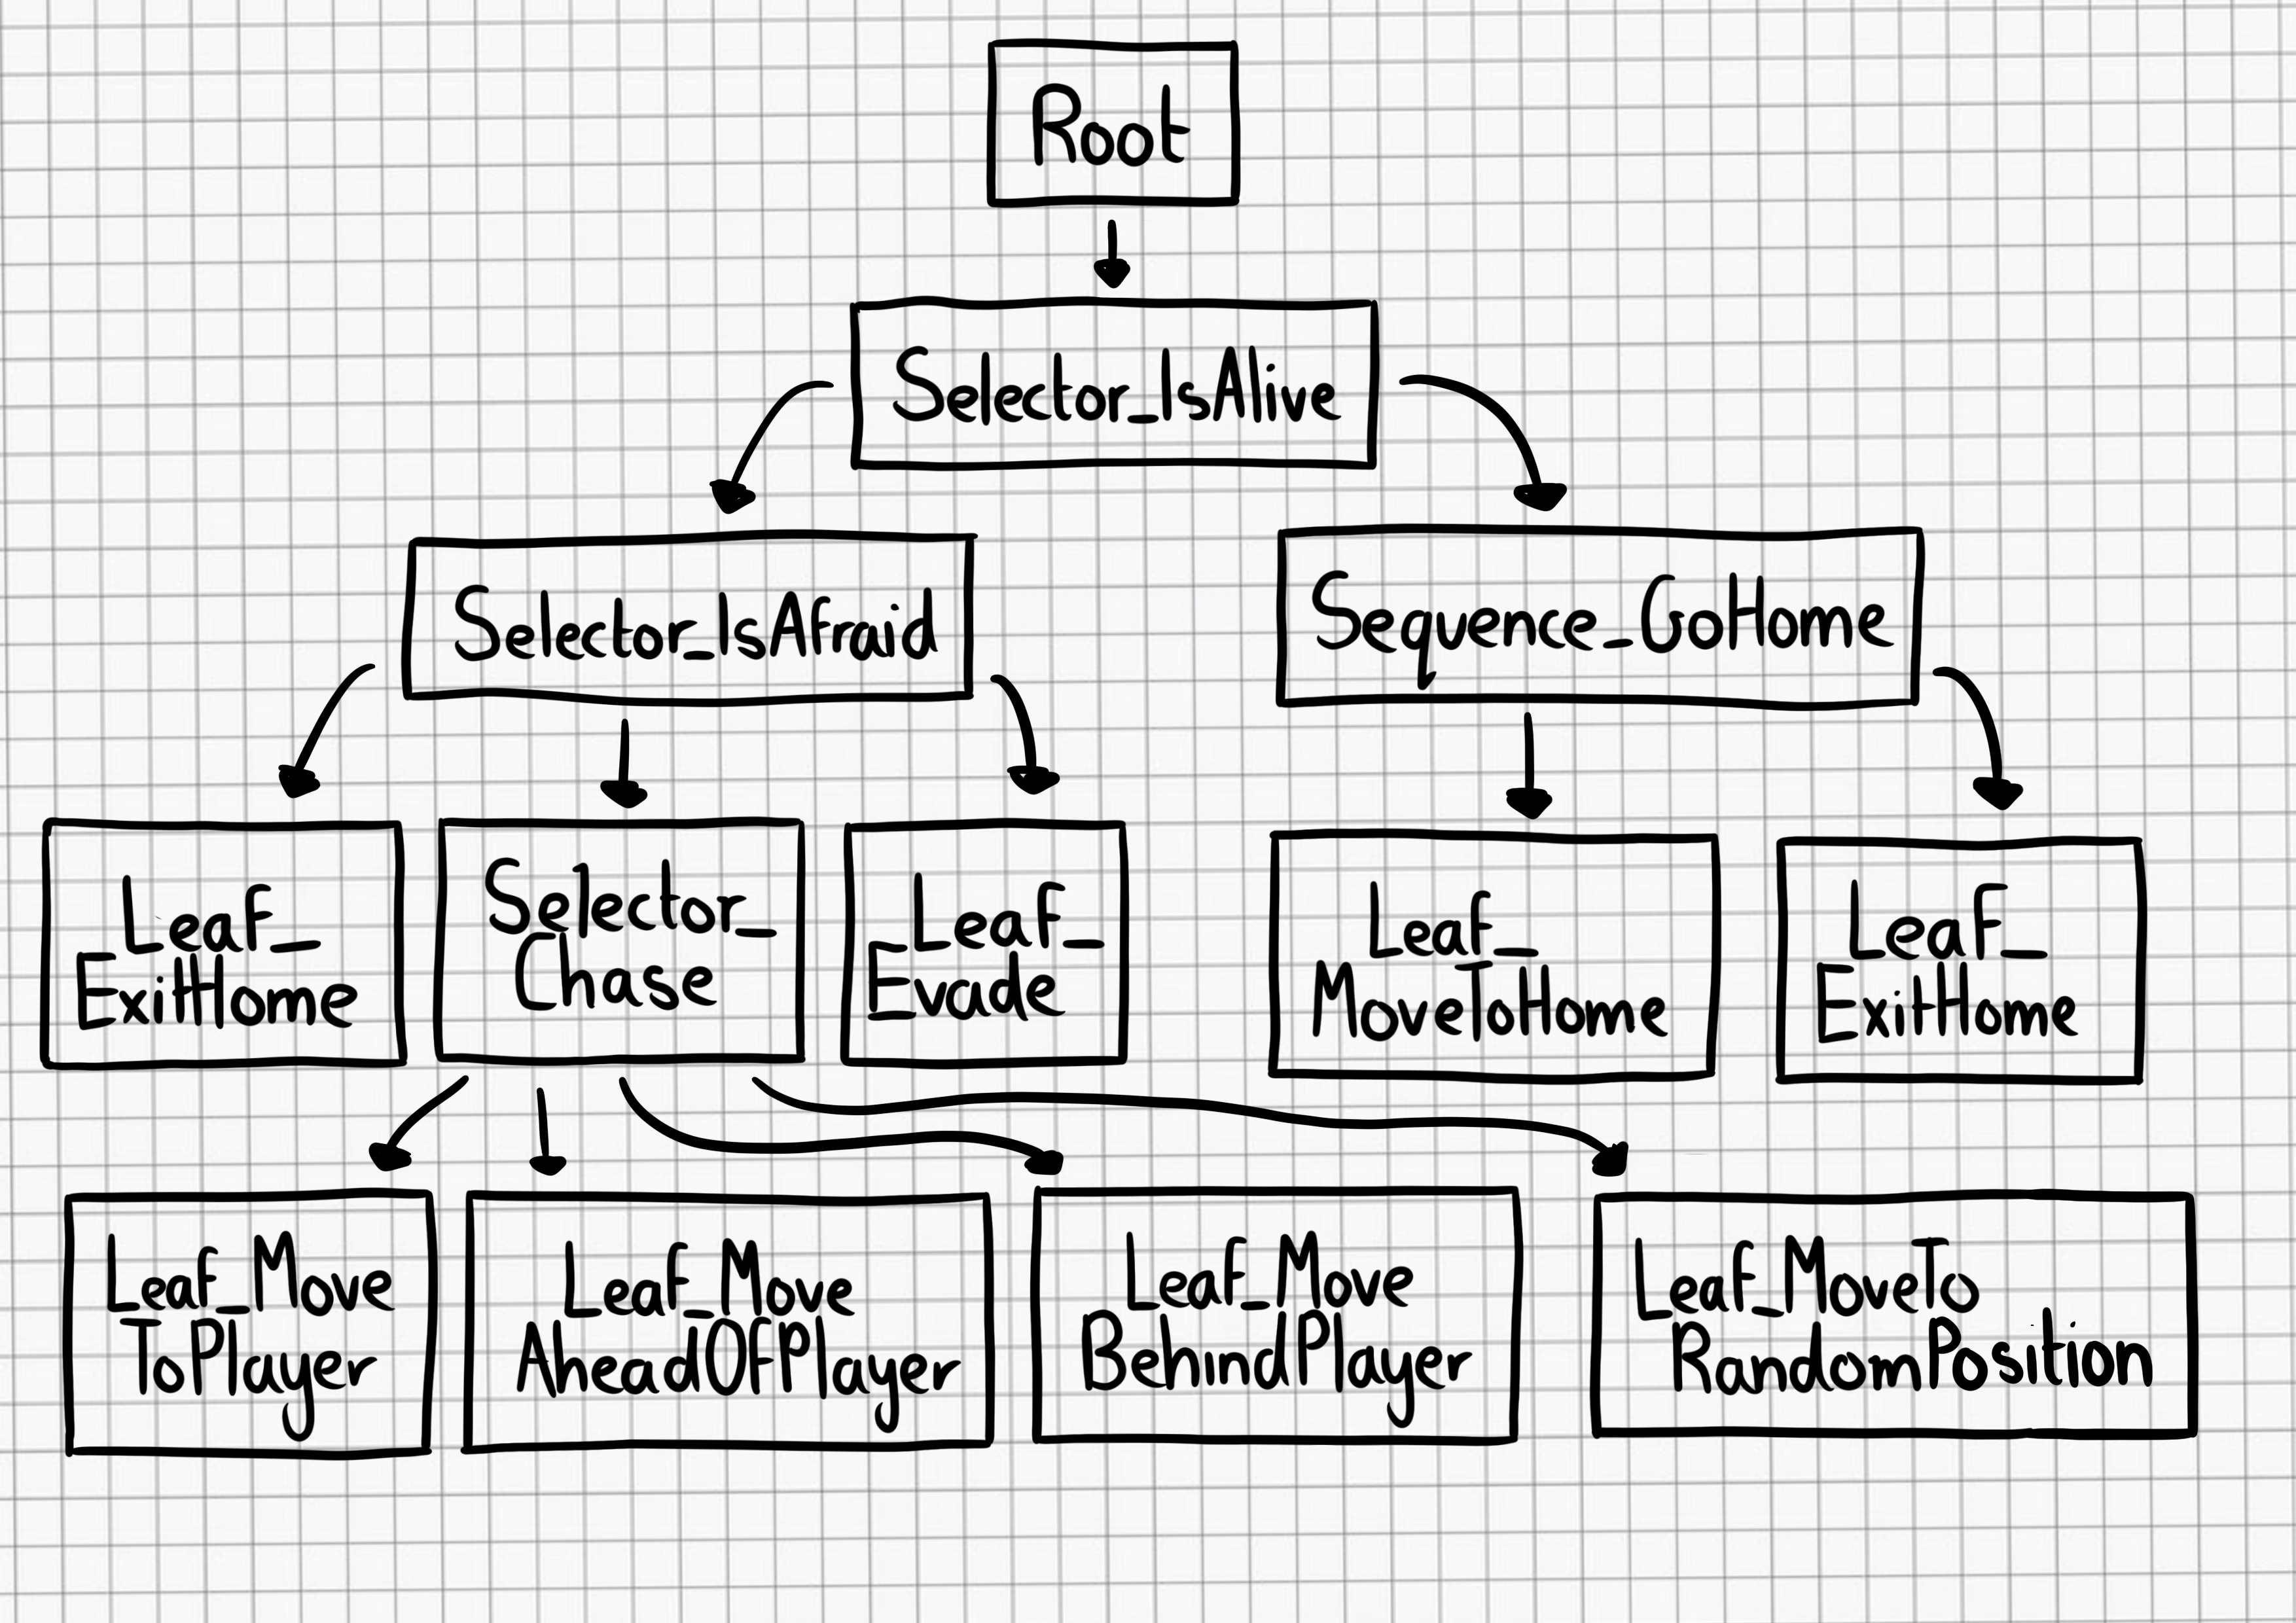
In 2002, Halo 2 programmer Damian Isla expanded on the idea of HFSM in a way that made it more scalable and modular for the game’s AI. This became known as the behaviour tree approach. It’s now a staple in AI game development. The behaviour tree is made up of nodes, which can be one of three types – composite, decorator, or leaf nodes. Each has a different function within the tree and affects the flow through the tree. Figure 3 shows how this approach is set up for our Unity project. The states we’ve explored so far are called leaf nodes. Leaf nodes end a particular branch of the tree and don’t have child nodes – these are where the AI behaviours are located. For example, Leaf_ExitHome, Leaf_Evade, and Leaf_ MoveAheadOfPlayer all tell the ghost where to move to. Composite nodes can have multiple child nodes and are used to determine the order in which the children are called. This could be in the order in which they’re described by the tree, or by selection, where the children nodes will compete, with the parent node selecting which child node gets the go-ahead. Selector_Chase allows the ghost to select a single path down the tree by choosing a random option, whereas Sequence_ GoHome has to complete all the child paths to complete its behaviour.

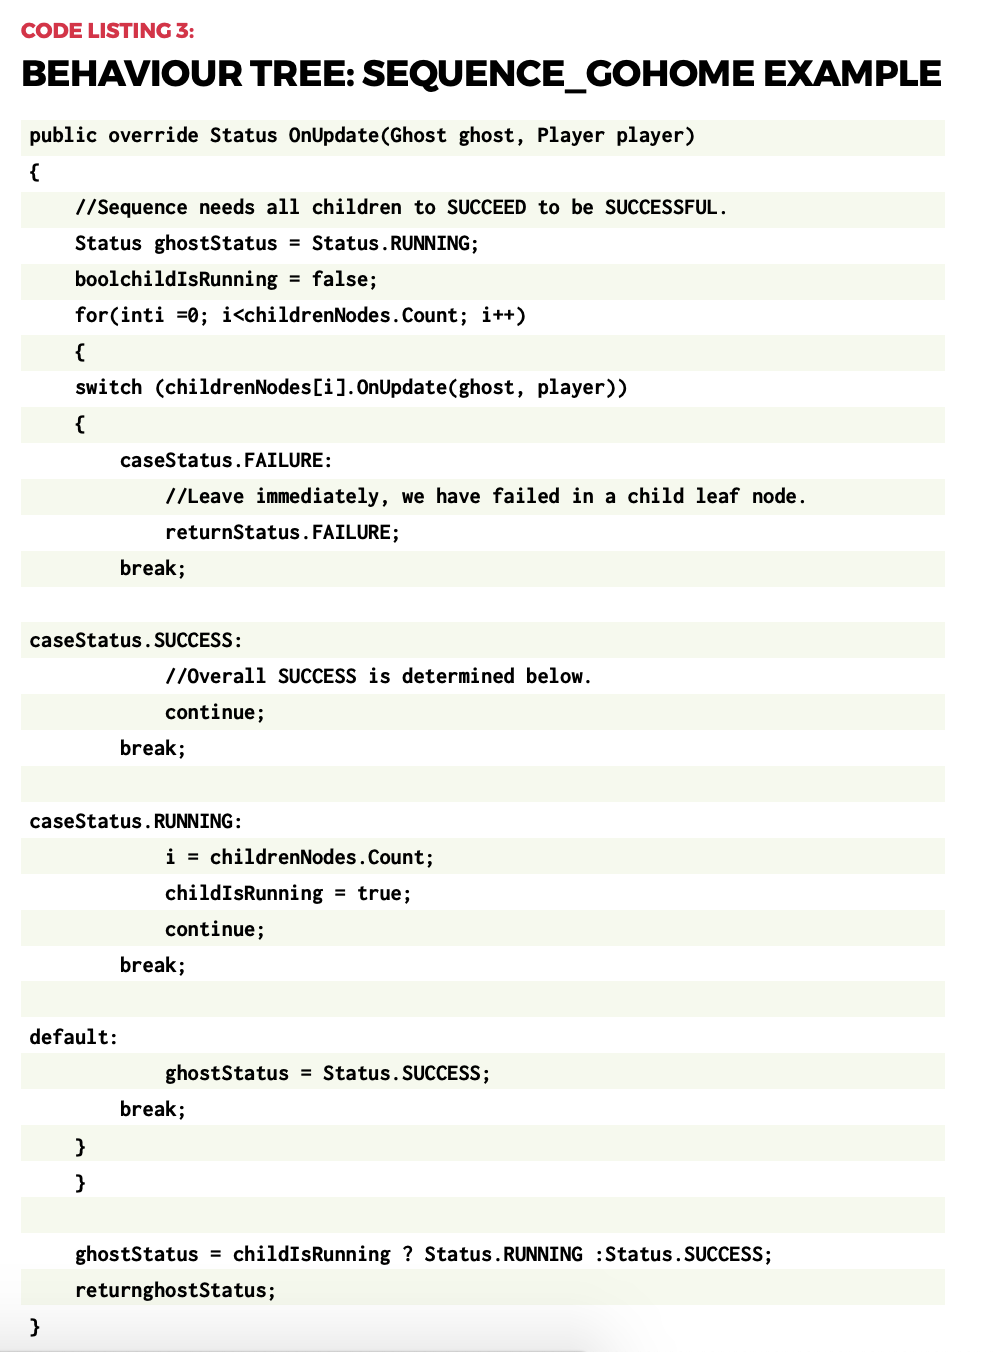
Code Listing 2 shows how simple it is to choose a random behaviour to use – just be sure to store the index for the next update. Code Listing 3 demonstrates how to go through all child nodes, and to return SUCCESS only when all have completed, otherwise the status RUNNING is returned. FAILURE only gets returned when a child node itself returns a FAILURE status.

Complex behaviours

Although not used in our example project, behaviour trees can also have nodes called decorators. A decorator node can only have a single child, and can modify the result returned. For example, a decorator may iterate the child node for a set period, perhaps indefinitely, or even flip the result returned from being a success to a failure. From what first appears to be a collection of simple concepts, complex behaviours can then develop.

Figure 3: Behaviour tree

Video game AI is all about the illusion of intelligence. As long as the characters are believable in their context, the player should maintain their immersion in the game world and enjoy the experience we’ve made. Hopefully, the approaches introduced here highlight how even simple approaches can be used to develop complex characters. This is just the tip of the iceberg: AI development is a complex subject, but it’s also fun and rewarding to explore.

Wireframe #43, with the gorgeous Sea of Stars on the cover.

The latest issue of Wireframe Magazine is out now. available in print from the Raspberry Pi Press onlinestore, your local newsagents, and the Raspberry Pi Store, Cambridge.

You can also download the PDF directly from the Wireframe Magazine website.

The post AI-Man: a handy guide to video game artificial intelligence appeared first on Raspberry Pi.