We don’t have a useful quantum computer yet, but we do have quantum algorithms. Shor’s algorithm has the potential to factor large numbers faster than otherwise possible, which—if the run times are actually feasible—could break both the RSA and Diffie-Hellman public-key algorithms.
Now, computer scientist Oded Regev has a significant speed-up to Shor’s algorithm, at the cost of more storage.
The improvement was profound. The number of elementary logical steps in the quantum part of Regev’s algorithm is proportional to n1.5 when factoring an n-bit number, rather than n2 as in Shor’s algorithm. The algorithm repeats that quantum part a few dozen times and combines the results to map out a high-dimensional lattice, from which it can deduce the period and factor the number. So the algorithm as a whole may not run faster, but speeding up the quantum part by reducing the number of required steps could make it easier to put it into practice.
Of course, the time it takes to run a quantum algorithm is just one of several considerations. Equally important is the number of qubits required, which is analogous to the memory required to store intermediate values during an ordinary classical computation. The number of qubits that Shor’s algorithm requires to factor an n-bit number is proportional to n, while Regev’s algorithm in its original form requires a number of qubits proportional to n1.5—a big difference for 2,048-bit numbers.
Again, this is all still theoretical. But now it’s theoretically faster.
The dust has settled after another re:Invent. I once again had the privilege of organizing the DevOps and Developer Productivity (DOP) track along with Jessie VanderVeen, Anubhav Rao and countless others. For 2022, the DOP track included 59 sessions. If you weren’t able to attend, I have compiled a list of the on-demand sessions for you below.
DOP225 – Build without limits: The next-generation developer experience at AWS – Join this talk to explore the next-generation AWS developer experience. Adam Seligman, Vice President of AWS Generative Builders, provides updates on the latest AWS developer tools and services, including capabilities powered by generative AI, low-code abstractions, cloud development, and operations. See demos of key developer services and how they integrate to help enhance productivity and innovation. Discover how AWS is empowering builders of virtually all skill levels to build, deploy, and scale resilient cloud applications quickly. Learn how the continuous evolution of AWS developer tools and integration and cloud capabilities creates new opportunities to innovate and accomplish more.
DOP201 – Best practices for Amazon CodeWhisperer – Generative AI can create new content and ideas, including conversations, stories, images, videos, and music. Learning how to interact with generative AI effectively and proficiently is a skill worth developing. Join this session to learn about best practices for engaging with Amazon CodeWhisperer, which uses an underlying foundation model to radically improve developer productivity by generating code suggestions in real time.
DOP202 – Realizing the developer productivity benefits of Amazon CodeWhisperer – Developers spend a significant amount of their time writing undifferentiated code. Amazon CodeWhisperer radically improves productivity by generating code suggestions in real time to alleviate this burden. In this session, learn how CodeWhisperer can “write” much of this undifferentiated code, allowing developers to focus on business logic and accelerate the pace of their innovation.
DOP205 – Accelerate DevOps with generative AI and Amazon CodeCatalyst – In this session, see a demo of the newest generative AI features in Amazon CodeCatalyst. Learn how you can input simple instructions to produce ready-to-use code, automatically adjust infrastructure, and update CI/CD workflows. Explore how you can generate concise summaries of intricate pull requests. Join this session to see firsthand how these practical additions to CodeCatalyst simplify application delivery, improve team collaboration, and speed up the software development lifecycle from concept to deployment. Discover the groundbreaking impact that AI can have on DevOps through the lens of CodeCatalyst.
DOP206 – AWS infrastructure as code: A year in review – AWS provides services that help with the creation, deployment, and maintenance of application infrastructure in a programmatic, descriptive, and declarative way. These services help provide rigor, clarity, and reliability to application development. Join this session to learn about the new features and improvements for AWS infrastructure as code with AWS CloudFormation and AWS Cloud Development Kit (AWS CDK) and how they can benefit your team.
DOP207 – Build and run it: Streamline DevOps with machine learning on AWS – While organizations have improved how they deliver and operate software, development teams still run into issues when performing manual code reviews, looking for hard-to-find defects, and uncovering security-related problems. Developers have to keep up with multiple programming languages and frameworks, and their productivity can be impaired when they have to search online for code snippets. Additionally, they require expertise in observability to successfully operate the applications they build. In this session, learn how companies like Fidelity Investments use machine learning–powered tools like Amazon CodeWhisperer and Amazon DevOps Guru to boost application availability and write software faster and more reliably.
DOP208 – Continuous integration and delivery for AWS – AWS provides one place where you can plan work, collaborate on code, build, test, and deploy applications with continuous integration/continuous delivery (CI/CD) tools. In this session, learn about how to create end-to-end CI/CD pipelines using infrastructure as code on AWS.
DOP209 – Governance and security with infrastructure as code – In this session, learn how to use AWS CloudFormation and the AWS CDK to deploy cloud applications in regulated environments while enforcing security controls. Find out how to catch issues early with cdk-nag, validate your pipelines with cfn-guard, and protect your accounts from unintended changes with CloudFormation hooks.
DOP210 – Introducing Amazon CodeCatalyst Enterprise – Amazon CodeCatalyst brings together the things you need to build, deploy, and collaborate on software on AWS into one integrated software development service. With CodeCatalyst Enterprise, organizations can now deliver a pre-paved path to production that complies with IT and security policies and integrates with existing infrastructure investments such as identity and access management (IAM), virtual private cloud (VPC), and custom blueprints. This helps platform engineers and IT to deliver a flexible yet compliant way for developers to start building and collaborating on new software projects in minutes. Join this session to discover the new ways that CodeCatalyst helps enterprise developers build and ship code faster while spending more time doing the work they love.
DOP211 – Boost developer productivity with Amazon CodeWhisperer – Generative AI is transforming the way that developers work. Writing code is already getting disrupted by tools like Amazon CodeWhisperer, which enhances developer productivity by providing real-time code completions based on natural language prompts. In this session, get insights into how to evaluate and measure productivity with the adoption of generative AI–powered tools. Learn from the AWS Disaster Recovery team who uses CodeWhisperer to solve complex engineering problems by gaining efficiency through longer productivity cycles and increasing velocity to market for ongoing fixes. Hear how integrating tools like CodeWhisperer into your workflows can boost productivity.
DOP212 – New AWS generative AI features and tools for developers – Explore how generative AI coding tools are changing the way developers and companies build software. Generative AI–powered tools are boosting developer and business productivity by automating tasks, improving communication and collaboration, and providing insights that can inform better decision-making. In this session, see the newest AWS tools and features that make it easier for builders to solve problems with minimal technical expertise and that help technical teams boost productivity. Walk through how organizations like FINRA are exploring generative AI and beginning their journey using these tools to accelerate their pace of innovation.
DOP220 – Simplify building applications with AWS SDKs – AWS SDKs play a vital role in using AWS services in your organization’s applications and services. In this session, learn about the current state and the future of AWS SDKs. Explore how they can simplify your developer experience and unlock new capabilities. Discover how SDKs are evolving, providing a consistent experience in multiple languages and empowering you to do more with high-level abstractions to make it easier to build on AWS. Learn how AWS SDKs are built using open source tools like Smithy, and how you can use these tools to build your own SDKs to serve your customers’ needs.
DOP228 – Amazon Q: Your new assistant and expert guide for building with AWS – In this session, learn how Amazon Q is transforming the developer experience by speeding up a range of tasks as you research how to get started, evaluate system design, build secure and scalable applications, upgrade existing applications, and optimize application performance. Learn firsthand how Amazon Q capabilities for building, troubleshooting, and transforming applications faster and more easily frees you up to focus on experimentation and innovation.
DOP229 – Automate app upgrades & maintenance using Amazon Q Code Transformation – Developers spend significant time completing the undifferentiated work of maintaining and upgrading legacy applications. Teams need to balance investments in building new features with mandatory patching and update work. Now, using the power of generative AI, Amazon Q can expedite these critical upgrade tasks, transforming applications to use the latest language features and versions. Join the session to learn how your team can automate Java application upgrades and soon port .NET framework applications to cross-platform .NET.
As we kick off 2024, I wanted to take a moment to highlight the top posts from 2023. Without further ado, here are the top 10 AWS DevOps blog posts of 2023.
Unit Testing AWS Lambda with Python and Mock AWS Services – When building serverless event-driven applications using AWS Lambda, it is best practice to validate individual components. Unit testing can quickly identify and isolate issues in AWS Lambda function code. The techniques outlined in this blog demonstrates unit test techniques for Python-based AWS Lambda functions and interactions with AWS Services.
How to use Amazon CodeWhisperer using Okta as an external IdP – Customers using Amazon CodeWhisperer often want to enable their developers to sign in using existing identity providers (IdP), such as Okta. CodeWhisperer provides support for authentication either through AWS Builder Id or AWS IAM Identity Center. AWS Builder ID is a personal profile for builders. It is designed for individual developers, particularly when working on personal projects or in cases when organization does not authenticate to AWS using the IAM Identity Center. IAM Identity Center is better suited for enterprise developers who use CodeWhisperer as employees of organizations that have an AWS account. The IAM Identity Center authentication method expands the capabilities of IAM by centralizing user administration and access control. Many customers prefer using Okta as their external IdP for Single Sign-On (SSO). They aim to leverage their existing Okta credentials to seamlessly access CodeWhisperer. To achieve this, customers utilize the IAM Identity Center authentication method.
Introducing Amazon CodeWhisperer for command line – The command line is used by over thirty million engineers to write, build, run, debug, and deploy software. However, despite how critical it is to the software development process, the command line is notoriously hard to use. Its output is terse, its interface is from the 1970s, and it offers no hints about the ‘right way’ to use it. With tens of thousands of command line applications (called command-line interfaces or CLIs), it’s almost impossible to remember the correct input syntax. The command line’s lack of input validation also means typos can cause unnecessary errors, security risks, and even production outages. It’s no wonder that most software engineers find the command line an error-prone and often frustrating experience.
10 ways to build applications faster with Amazon CodeWhisperer – Amazon CodeWhisperer is a powerful generative AI tool that gives me coding superpowers. Ever since I have incorporated CodeWhisperer into my workflow, I have become faster, smarter, and even more delighted when building applications. However, learning to use any generative AI tool effectively requires a beginner’s mindset and a willingness to embrace new ways of working.
Secure CDK deployments with IAM permission boundaries – The AWS Cloud Development Kit (CDK) accelerates cloud development by allowing developers to use common programming languages when modelling their applications. To take advantage of this speed, developers need to operate in an environment where permissions and security controls don’t slow things down, and in a tightly controlled environment this is not always the case. Of particular concern is the scenario where a developer has permission to create AWS Identity and Access Management (IAM) entities (such as users or roles), as these could have permissions beyond that of the developer who created them, allowing for an escalation of privileges. This approach is typically controlled through the use of permission boundaries for IAM entities, and in this post you will learn how these boundaries can now be applied more effectively to CDK development – allowing developers to stay secure and move fast.
How to import existing resources into AWS CDK Stacks – Many customers have provisioned resources through the AWS Management Console or different Infrastructure as Code (IaC) tools, and then started using AWS Cloud Development Kit (AWS CDK) in a later stage. After introducing AWS CDK into the architecture, you might want to import some of the existing resources to avoid losing data or impacting availability.
Develop a serverless application in Python using Amazon CodeWhisperer – While writing code to develop applications, developers must keep up with multiple programming languages, frameworks, software libraries, and popular cloud services from providers such as AWS. Even though developers can find code snippets on developer communities, to either learn from them or repurpose the code, manually searching for the snippets with an exact or even similar use case is a distracting and time-consuming process. They have to do all of this while making sure that they’re following the correct programming syntax and best coding practices.
Optimize software development with Amazon CodeWhisperer – Businesses differentiate themselves by delivering new capabilities to their customers faster. They must leverage automation to accelerate their software development by optimizing code quality, improving performance, and ensuring their software meets security/compliance requirements. Trained on billions of lines of Amazon and open-source code, Amazon CodeWhisperer is an AI coding companion that helps developers write code by generating real-time whole-line and full-function code suggestions in their IDEs. Amazon CodeWhisperer has two tiers: the individual tier is free for individual use, and the professional tier provides administrative capabilities for organizations seeking to grant their developers access to CW. This blog provides a high-level overview of how developers can use CodeWhisperer.
How to write and execute integration tests for AWS CDK applications – Automated integration testing validates system components and boosts confidence for new software releases. Performing integration tests on resources deployed to the AWS cloud enables the validation of AWS Identity and Access Management (IAM) policies, service limits, application configuration, and runtime code. For developers that are currently leveraging AWS Cloud Development Kit (AWS CDK) as their Infrastructure as Code tool, there is a testing framework available that makes integration testing easier to implement in the software release.
Building NET 7 Applications with AWS CodeBuild – AWS CodeBuild is a fully managed DevOps service for building and testing your applications. As a fully managed service, there is no infrastructure to manage and you pay only for the resources that you use when you are building your applications. CodeBuild provides a default build image that contains the current Long Term Support (LTS) version of the .NET SDK.
A big thank you to all our readers! Your feedback and collaboration are appreciated and help us produce better content.
Kaspersky researchers are detailing “an attack that over four years backdoored dozens if not thousands of iPhones, many of which belonged to employees of Moscow-based security firm Kaspersky.” It’s a zero-click exploit that makes use of four iPhone zero-days.
The most intriguing new detail is the targeting of the heretofore-unknown hardware feature, which proved to be pivotal to the Operation Triangulation campaign. A zero-day in the feature allowed the attackers to bypass advanced hardware-based memory protections designed to safeguard device system integrity even after an attacker gained the ability to tamper with memory of the underlying kernel. On most other platforms, once attackers successfully exploit a kernel vulnerability they have full control of the compromised system.
On Apple devices equipped with these protections, such attackers are still unable to perform key post-exploitation techniques such as injecting malicious code into other processes, or modifying kernel code or sensitive kernel data. This powerful protection was bypassed by exploiting a vulnerability in the secret function. The protection, which has rarely been defeated in exploits found to date, is also present in Apple’s M1 and M2 CPUs.
Here is a quick rundown of this 0-click iMessage attack, which used four zero-days and was designed to work on iOS versions up to iOS 16.2.
Attackers send a malicious iMessage attachment, which the application processes without showing any signs to the user.
This attachment exploits the remote code execution vulnerability CVE-2023-41990 in the undocumented, Apple-only ADJUST TrueType font instruction. This instruction had existed since the early nineties before a patch removed it.
It uses return/jump oriented programming and multiple stages written in the NSExpression/NSPredicate query language, patching the JavaScriptCore library environment to execute a privilege escalation exploit written in JavaScript.
This JavaScript exploit is obfuscated to make it completely unreadable and to minimize its size. Still, it has around 11,000 lines of code, which are mainly dedicated to JavaScriptCore and kernel memory parsing and manipulation.
It exploits the JavaScriptCore debugging feature DollarVM ($vm) to gain the ability to manipulate JavaScriptCore’s memory from the script and execute native API functions.
It was designed to support both old and new iPhones and included a Pointer Authentication Code (PAC) bypass for exploitation of recent models.
It uses the integer overflow vulnerability CVE-2023-32434 in XNU’s memory mapping syscalls (mach_make_memory_entry and vm_map) to obtain read/write access to the entire physical memory of the device at user level.
It uses hardware memory-mapped I/O (MMIO) registers to bypass the Page Protection Layer (PPL). This was mitigated as CVE-2023-38606.
After exploiting all the vulnerabilities, the JavaScript exploit can do whatever it wants to the device including running spyware, but the attackers chose to: (a) launch the IMAgent process and inject a payload that clears the exploitation artefacts from the device; (b) run a Safari process in invisible mode and forward it to a web page with the next stage.
The web page has a script that verifies the victim and, if the checks pass, receives the next stage: the Safari exploit.
The Safari exploit uses CVE-2023-32435 to execute a shellcode.
The shellcode executes another kernel exploit in the form of a Mach object file. It uses the same vulnerabilities: CVE-2023-32434 and CVE-2023-38606. It is also massive in terms of size and functionality, but completely different from the kernel exploit written in JavaScript. Certain parts related to exploitation of the above-mentioned vulnerabilities are all that the two share. Still, most of its code is also dedicated to parsing and manipulation of the kernel memory. It contains various post-exploitation utilities, which are mostly unused.
The exploit obtains root privileges and proceeds to execute other stages, which load spyware. We covered these stages in our previous posts.
This is nation-state stuff, absolutely crazy in its sophistication. Kaspersky discovered it, so there’s no speculation as to the attacker.
A helpful summary of which US retail stores are using facial recognition, thinking about using it, or currently not planning on using it. (This, of course, can all change without notice.)
Three years ago, I wrote that campaigns to ban facial recognition are too narrow. The problem here is identification, correlation, and then discrimination. There’s no difference whether the identification technology is facial recognition, the MAC address of our phones, gait recognition, license plate recognition, or anything else. Facial recognition is just the easiest technology right now.
Kinesis Agent is a standalone Java software application that offers a straightforward way to collect and send data to Amazon Kinesis Data Streams and Amazon Kinesis Data Firehose. The agent continuously monitors a set of files and sends new data to the desired destination. The agent handles file rotation, checkpointing, and retry upon failures. It delivers all of your data in a reliable, timely, and simple manner. It also emits Amazon CloudWatch metrics to help you better monitor and troubleshoot the streaming process.
This post describes the steps to send data from a containerized application to Kinesis Data Firehose using Kinesis Agent. More specifically, we show how to run Kinesis Agent as a sidecar container for an application running in Amazon Elastic Container Service (Amazon ECS). After the data is in Kinesis Data Firehose, it can be sent to any supported destination, such as Amazon Simple Storage Service (Amazon S3).
In order to present the key points required for this setup, we assume that you are familiar with Amazon ECS and working with containers. We also avoid the implementation details and packaging process of our test data generation application, referred to as the producer.
Solution overview
As depicted in the following figure, we configure a Kinesis Agent container as a sidecar that can read files created by the producer container. In this instance, the producer and Kinesis Agent containers share data via a bind mount in Amazon ECS.
Prerequisites
You should satisfy the following prerequisites for the successful completion of this task:
Familiarity working with containers and Amazon ECS
With these prerequisites in place, you can begin next step to package a Kinesis Agent and your desired agent configuration as a container in your local development machine.
Create a Kinesis Agent configuration file
We use the Kinesis Agent configuration file to configure the source and destination, among other data transfer settings. The following code uses the minimal configuration required to read the contents of files matching /var/log/producer/*.log and publish them to a Kinesis Data Firehose delivery stream called kinesis-agent-demo:
To deploy Kinesis Agent as a sidecar in Amazon ECS, you first have to package it as a container image. The container must have Kinesis Agent, which and find binaries, and the Kinesis Agent configuration file that you prepared earlier. Its entry point must be configured using the start-aws-kinesis-agent script. This command is installed when you run the yum install aws-kinesis-agent step. The resulting Dockerfile should look as follows:
FROM amazonlinux

RUN yum install -y aws-kinesis-agent which findutils
COPY agent.json /etc/aws-kinesis/agent.json

CMD ["start-aws-kinesis-agent"]
Run the docker build command to build this container:
docker build -t kinesis-agent .
After the image is built, it should be pushed to a container registry like Amazon ECR so that you can reference it in the next section.
Create an ECS task definition with Kinesis Agent and the application container
Now that you have Kinesis Agent packaged as a container image, you can use it in your ECS task definitions to run as sidecar. To do that, you create an ECS task definition with your application container (called producer) and Kinesis Agent container. All containers in a task definition are scheduled on the same container host and therefore can share resources such as bind mounts.
In the following sample container definition, we use a bind mount called logs_dir to share a directory between the producer container and kinesis-agent container.
You can use the following template as a starting point, but be sure to change taskRoleArn and executionRoleArn to valid IAM roles in your AWS account. In this instance, the IAM role used for taskRoleArn must have write permissions to Kinesis Data Firehose that you specified earlier in the agent.json file. Additionally, make sure that the ECR image paths and awslogs-region are modified as per your AWS account.
Finally, you can run a new ECS task using the task definition you just created using the aws ecs run-task command. When the task is started, you should be able to see two containers running under that task on the Amazon ECS console.
Conclusion
This post showed how straightforward it is to run Kinesis Agent in a containerized environment. Although we used Amazon ECS as our container orchestration service in this post, you can use a Kinesis Agent container in other environments such as Amazon Elastic Kubernetes Service (Amazon EKS).
Buddhike de Silva is a Senior Specialist Solutions Architect at Amazon Web Services. Buddhike helps customers run large scale streaming analytics workloads on AWS and make the best out of their cloud journey.
TikTok seems to be skewing things in the interests of the Chinese Communist Party. (This is a serious analysis, and the methodology looks sound.)
Conclusion: Substantial Differences in Hashtag Ratios Raise
Concerns about TikTok’s Impartiality
Given the research above, we assess a strong possibility that content on TikTok is either amplified or suppressed based on its alignment with the interests of the Chinese Government. Future research should aim towards a more comprehensive analysis to determine the potential influence of TikTok on popular public narratives. This research should determine if and how TikTok might be utilized for furthering national/regional or international objectives of the Chinese Government.
To test PIGEON’s performance, I gave it five personal photos from a trip I took across America years ago, none of which have been published online. Some photos were snapped in cities, but a few were taken in places nowhere near roads or other easily recognizable landmarks.
That didn’t seem to matter much.
It guessed a campsite in Yellowstone to within around 35 miles of the actual location. The program placed another photo, taken on a street in San Francisco, to within a few city blocks.
Not every photo was an easy match: The program mistakenly linked one photo taken on the front range of Wyoming to a spot along the front range of Colorado, more than a hundred miles away. And it guessed that a picture of the Snake River Canyon in Idaho was of the Kawarau Gorge in New Zealand (in fairness, the two landscapes look remarkably similar).
This kind of thing will likely get better. And even if it is not perfect, it has some pretty profound privacy implications (but so did geolocation in the EXIF data that accompanies digital photos).
Sqids (pronounced “squids”) is an open-source library that lets you generate YouTube-looking IDs from numbers. These IDs are short, can be generated from a custom alphabet and are guaranteed to be collision-free.
I haven’t dug into the details enough to know how they can be guaranteed to be collision-free.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
Artificial intelligence is poised to upend much of society, removing human limitations inherent in many systems. One such limitation is information and logistical bottlenecks in decision-making.
Traditionally, people have been forced to reduce complex choices to a small handful of options that don’t do justice to their true desires. Artificial intelligence has the potential to remove that limitation. And it has the potential to drastically change how democracy functions.
Imagine your next sit-down dinner and being able to have a long conversation with a chef about your meal. You could end up with a bespoke dinner based on your desires, the chef’s abilities and the available ingredients. This is possible if you are cooking at home or hosted by accommodating friends.
But it is infeasible at your average restaurant: The limitations of the kitchen, the way supplies have to be ordered and the realities of restaurant cooking make this kind of rich interaction between diner and chef impossible. You get a menu of a few dozen standardized options, with the possibility of some modifications around the edges.
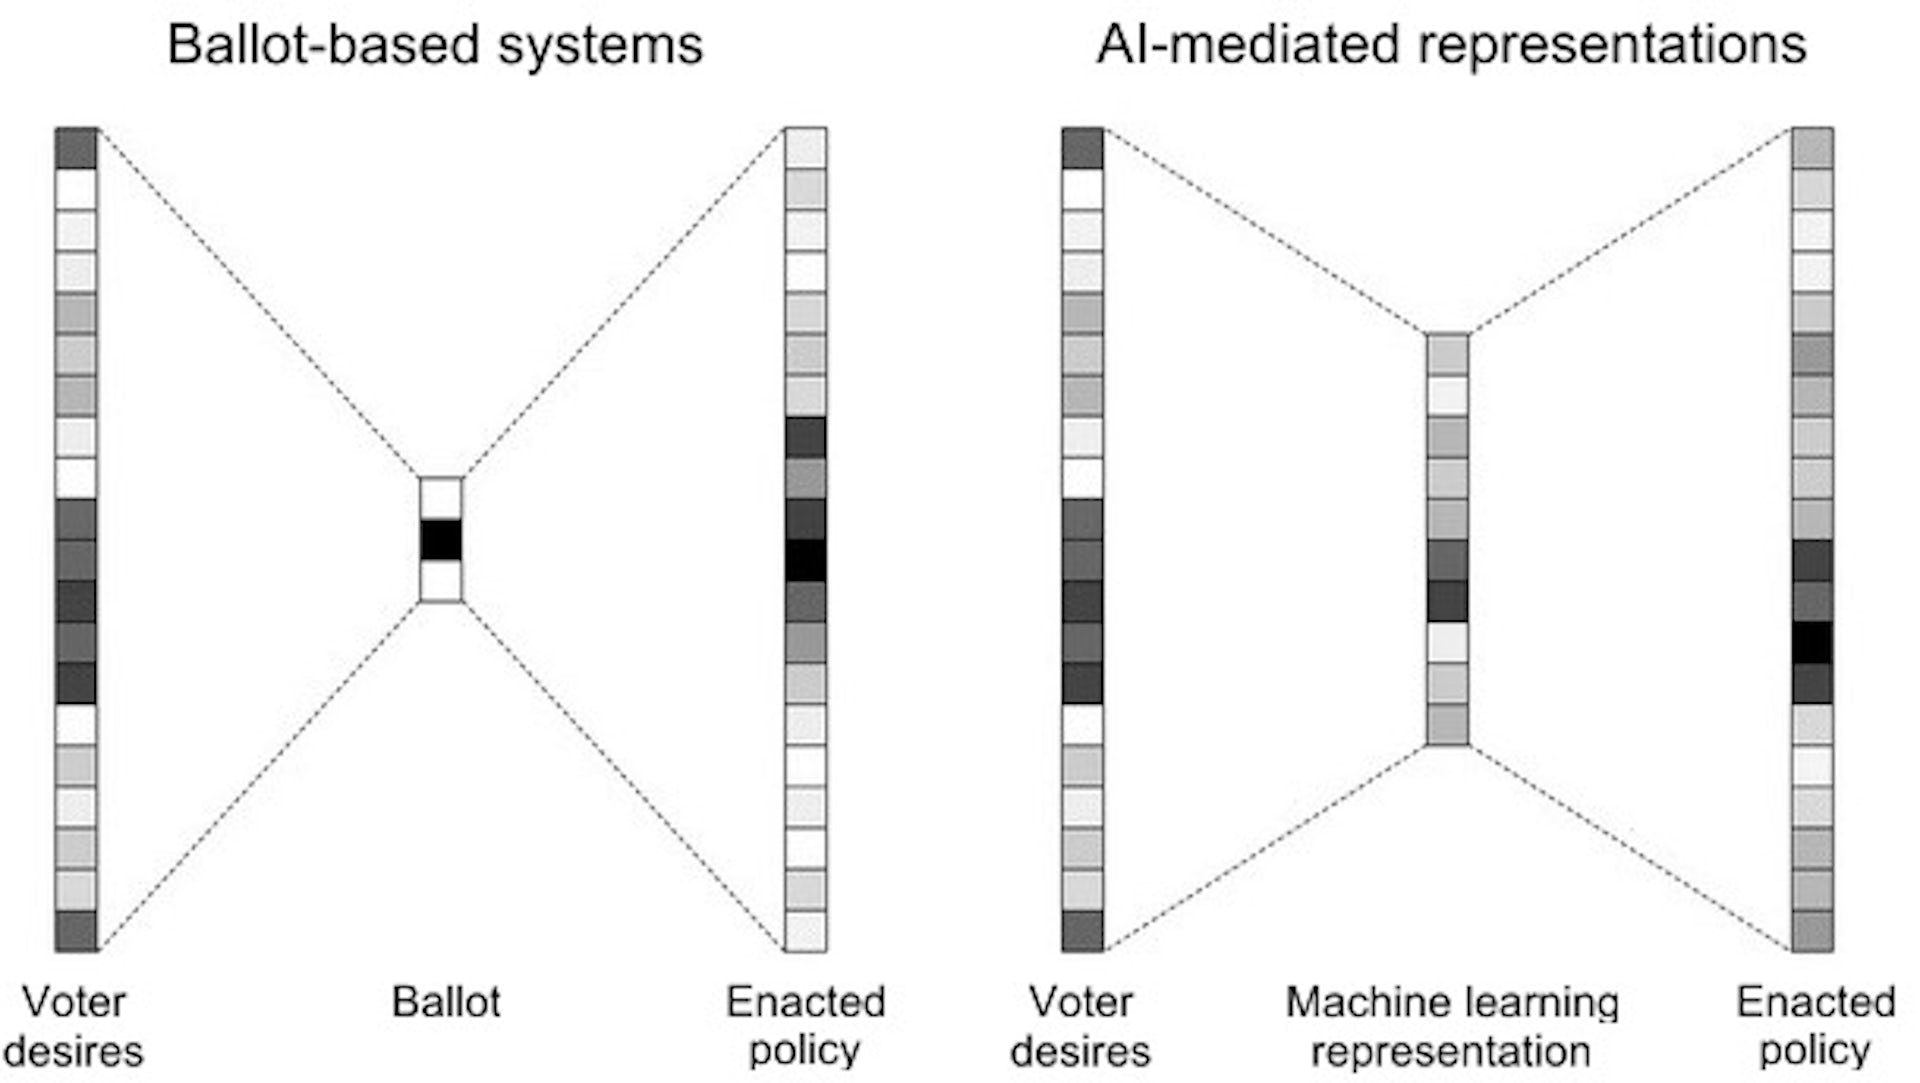
That’s a lossy bottleneck. Your wants and desires are rich and multifaceted. The array of culinary outcomes are equally rich and multifaceted. But there’s no scalable way to connect the two. People are forced to use multiple-choice systems like menus to simplify decision-making, and they lose so much information in the process.
People are so used to these bottlenecks that we don’t even notice them. And when we do, we tend to assume they are the inevitable cost of scale and efficiency. And they are. Or, at least, they were.
The possibilities
Artificial intelligence has the potential to overcome this limitation. By storing rich representations of people’s preferences and histories on the demand side, along with equally rich representations of capabilities, costs and creative possibilities on the supply side, AI systems enable complex customization at scale and low cost. Imagine walking into a restaurant and knowing that the kitchen has already started work on a meal optimized for your tastes, or being presented with a personalized list of choices.
There have been some early attempts at this. People have used ChatGPT to design meals based on dietary restrictions and what they have in the fridge. It’s still early days for these technologies, but once they get working, the possibilities are nearly endless. Lossy bottlenecks are everywhere.
Take labor markets. Employers look to grades, diplomas and certifications to gauge candidates’ suitability for roles. These are a very coarse representation of a job candidate’s abilities. An AI system with access to, for example, a student’s coursework, exams and teacher feedback as well as detailed information about possible jobs could provide much richer assessments of which employment matches do and don’t make sense.
Or apparel. People with money for tailors and time for fittings can get clothes made from scratch, but most of us are limited to mass-produced options. AI could hugely reduce the costs of customization by learning your style, taking measurements based on photos, generating designs that match your taste and using available materials. It would then convert your selections into a series of production instructions and place an order to an AI-enabled robotic production line.
Or software. Today’s computer programs typically use one-size-fits-all interfaces, with only minor room for modification, but individuals have widely varying needs and working styles. AI systems that observe each user’s interaction styles and know what that person wants out of a given piece of software could take this personalization far deeper, completely redesigning interfaces to suit individual needs.
Removing democracy’s bottleneck
These examples are all transformative, but the lossy bottleneck that has the largest effect on society is in politics. It’s the same problem as the restaurant. As a complicated citizen, your policy positions are probably nuanced, trading off between different options and their effects. You care about some issues more than others and some implementations more than others.
If you had the knowledge and time, you could engage in the deliberative process and help create better laws than exist today. But you don’t. And, anyway, society can’t hold policy debates involving hundreds of millions of people. So you go to the ballot box and choose between two—or if you are lucky, four or five—individual representatives or political parties.
Imagine a system where AI removes this lossy bottleneck. Instead of trying to cram your preferences to fit into the available options, imagine conveying your political preferences in detail to an AI system that would directly advocate for specific policies on your behalf. This could revolutionize democracy.
Ballots are bottlenecks that funnel a voter’s diverse views into a few options. AI representations of individual voters’ desires overcome this bottleneck, promising enacted policies that better align with voters’ wishes. Tantum Collins, CC BY-ND
One way is by enhancing voter representation. By capturing the nuances of each individual’s political preferences in a way that traditional voting systems can’t, this system could lead to policies that better reflect the desires of the electorate. For example, you could have an AI device in your pocket—your future phone, for instance—that knows your views and wishes and continually votes in your name on an otherwise overwhelming number of issues large and small.
Combined with AI systems that personalize political education, it could encourage more people to participate in the democratic process and increase political engagement. And it could eliminate the problems stemming from elected representatives who reflect only the views of the majority that elected them—and sometimes not even them.
On the other hand, the privacy concerns resulting from allowing an AI such intimate access to personal data are considerable. And it’s important to avoid the pitfall of just allowing the AIs to figure out what to do: Human deliberation is crucial to a functioning democracy.
Also, there is no clear transition path from the representative democracies of today to these AI-enhanced direct democracies of tomorrow. And, of course, this is still science fiction.
First steps
These technologies are likely to be used first in other, less politically charged, domains. Recommendation systems for digital media have steadily reduced their reliance on traditional intermediaries. Radio stations are like menu items: Regardless of how nuanced your taste in music is, you have to pick from a handful of options. Early digital platforms were only a little better: “This person likes jazz, so we’ll suggest more jazz.”
Today’s streaming platforms use listener histories and a broad set of features describing each track to provide each user with personalized music recommendations. Similar systems suggest academic papers with far greater granularity than a subscription to a given journal, and movies based on more nuanced analysis than simply deferring to genres.
A world without artificial bottlenecks comes with risks—loss of jobs in the bottlenecks, for example—but it also has the potential to free people from the straitjackets that have long constrained large-scale human decision-making. In some cases—restaurants, for example—the impact on most people might be minor. But in others, like politics and hiring, the effects could be profound.
Apple is rolling out a new “Stolen Device Protection” feature that seems well thought out:
When Stolen Device Protection is turned on, Face ID or Touch ID authentication is required for additional actions, including viewing passwords or passkeys stored in iCloud Keychain, applying for a new Apple Card, turning off Lost Mode, erasing all content and settings, using payment methods saved in Safari, and more. No passcode fallback is available in the event that the user is unable to complete Face ID or Touch ID authentication.
For especially sensitive actions, including changing the password of the Apple ID account associated with the iPhone, the feature adds a security delay on top of biometric authentication. In these cases, the user must authenticate with Face ID or Touch ID, wait one hour, and authenticate with Face ID or Touch ID again. However, Apple said there will be no delay when the iPhone is in familiar locations, such as at home or work.
In Writer, users can enter a ChatGPT-like session to edit or create their documents. In this chat session, the LLM can retrieve information from sources on the web to assist users in creation of their documents. We show that attackers can prepare websites that, when a user adds them as a source, manipulate the LLM into sending private information to the attacker or perform other malicious activities.
The data theft can include documents the user has uploaded, their chat history or potentially specific private information the chat model can convince the user to divulge at the attacker’s behest.
The Solntsepek group has takencreditfortheattack. They’re linked to the Russian military, so it’s unclear whether the attack was government directed or freelance.
This is one of the most significant cyberattacks since Russia invaded in February 2022.
This blog post is written by Jose Guay, Technical Account Manger, Enterprise Support.
A typical option to reduce costs associated with running Amazon Elastic Compute Cloud (Amazon EC2) instances is to stop them when they are idle. However, there are scenarios where stopping an idle instance is not practical. For example, instances with development environments that take time to prepare and run which benefit from not needing to do this process every day. For these instances, hibernation is a better alternative.
This blog post explores a solution that will find idle instances using an Amazon CloudWatch alarm that monitors the instance’s CPU usage. When the CPU usage consistently drops below the alarm’s threshold, the alarm enters the ALARM state and raises an event used to identify the instance and trigger hibernation.
To hibernate an EC2 instance, there are prerequisites and required preparation. The instance must be configured to hibernate, and this is done when first launching it. This configuration cannot be changed after launching the instance.
One way to trigger instance hibernation is to use an AWS Lambda function. The Lambda function needs specific permissions configured with AWS Identity and Access Management (IAM). To connect the function with the alarm that detects the idle instance, use an Amazon EventBridge bus.
The following architecture diagram shows a solution.
Figure 1 – Solution architecture
An EC2 instance sends metrics to CloudWatch.
A CloudWatch alarm detects an idle instance and sends the event to EventBridge.
EventBridge triggers a Lambda function.
The Lambda function evaluates the execution role permissions.
The Lambda function identifies the instance and sends the hibernation signal.
To implement the solution, follow these steps:
Configure permissions with IAM
Create the Lambda function
Configure the EC2 instance to send metrics to CloudWatch
Configure EventBridge
a. Configure permissions with IAM
Create an IAM role with permissions to stop an EC2 instance. The Lambda function uses it as its execution role. The IAM role also needs permissions to save logs in CloudWatch. This is useful to log when an instance is entering hibernation.
For Select a service, search and select CloudWatch Logs.
In Actions allowed, search “createlog” and select CreateLogStream and CreateLogGroup.
Repeat the search, this time for “putlog”, and select PutLogEvents.
In Resources, choose All.
Select + Add more permissions.
For Select a service, select EC2.
In Actions allowed, search “stop” and select StopInstances from the results.
In Resources, choose Specific, and select the Add Arn
From the pop-up window select Resource in this account, type the region where the instance is, and the instance ID. This forms the ARN of the instances to monitor.
Select Add ARNs.
Select Next.
Name the policy AllowHibernateEC2InstancePolicy.
Figure 2 – IAM policy to access EC2 instances and CloudWatch logs
Figure 3 – Viewing the IAM policy in JSON format
In the navigation page, select Roles.
Select Create role.
For Trusted entity type, select AWS Service.
For Use case, select Lambda.
Select Next.
In the Permissions policies list, search and select Allow HibernateEC2InstancePolicy.
Select Next.
Name the role AllowHibernateEC2InstanceFromLambdaRole.
Select Create role.
Figure 4 – IAM role implementing the IAM policy
b. Create the Lambda function
Create a Lambda function that will find the ID of the idle instance using the event data from the CloudWatch alarm to hibernate it. The event data will be in a function parameter.
The event data is in the JSON format. The following is an example of what this data looks like.
For the Runtime, select Python 3.10 (or the latest Python version).
For Architecture, choose arm64.
Expand Change default execution role and select Use an existing role.
Select AllowHibernateEC2InstanceFromLambdaRole from the list of existing roles.
Select Create function at the bottom of the page.
In the Lambda function page, scroll down to view the Code tab at the bottom. Copy the following code onto the editor for the lambda_function.py file.
import boto3

def lambda_handler(event, context):
    instancesToHibernate = []
    region = getRegion(event)
    ec2Client = boto3.client('ec2', region_name=region)
    id = getInstanceId(event)

    if id is not None:
        instancesToHibernate.append(id)
        ec2Client.stop_instances(InstanceIds=instancesToHibernate, Hibernate=True)
        print('stopped instances: ' + str(instancesToHibernate) + ' in region ' + region)
    else:
        print('No instance id found')

def getRegion(payload):
    if 'region' in payload:
        region = payload['region']
        return region

    #default to N. Virginia
    return 'us-east-1'

def getInstanceId(payload):
    if 'detail' in payload:
        detail = payload['detail']
        if 'configuration' in detail:
            configuration = detail['configuration']
            if 'metrics' in configuration:
                if len(configuration['metrics']) > 0:
                    firstMetric = configuration['metrics'][0]
                    if 'metricStat' in firstMetric:
                        metricStat = firstMetric['metricStat']
                        if 'metric' in metricStat:
                            metric = metricStat['metric']
                            if 'dimensions' in metric:
                                dimensions = metric['dimensions']
                                if 'InstanceId' in dimensions:
                                    id = dimensions['InstanceId']
                                    return id

    return None
Figure 5 – Lambda function code editor
The code has the following contents:
Imports section. In this section, import the libraries that the function uses. In our case, the boto3
The main method, called lambda_handler, is the execution entry point. This is the method called whenever the Lambda function runs.
It defines an array to store the IDs of the instances that enter hibernation. This is necessary because the method stop_instances expects an array as opposed to a single value.
Using the event data, it finds the AWS Region and instance ID of the instance to hibernate.
It initializes the Amazon EC2 client by calling the client method.
If it finds an instance ID, then it adds it to the instances array.
Calls stop_instances passing as parameters the instances array and True to indicate the hibernation operation.
c. Configure the EC2 instance to send metrics to CloudWatch
In the scenario, an idle EC2 instance has its CPU utilization under 10% during a 15-minute period. Adjust the utilization percentage and/or period to meet your needs. To enable alarm tracking, the EC2 instance must send the CPU Usage metric to CloudWatch.
Select an instance to monitor with the checkbox on the left.
Find the Alarm status column, and select the plus sign to add a new alarm.
Figure 6 – Creating a new CloudWatch alarm from the EC2 console
In the Manage CloudWatch alarms page, select Create an alarm. Then, turn off Alarm action. Use Alarm notification to notify when hibernating an instance, otherwise, turn off.
Figure 7 – CloudWatch alarm notification and action settings
In the Alarm thresholds section, select:
Group samples by Average.
Type of data to sample CPU utilization.
Alarm when less than (<).
Percent 10.
Consecutive periods 1.
Period 15 Minutes.
Alarm name Idle-EC2-Instance-LessThan10Pct-CPUUtilization-15Min.
Figure 8 – CloudWatch alarm thresholds
Select Create at the bottom of the page.
A successful creation shows a green banner at the top of the page.
Select the Alarm status column for the instance, then select the link that shows in the pop-up window to go to the new CloudWatch alarm details.
Figure 9 – Accessing the CloudWatch alarm from the EC2 console
Scroll down to view the alarm details and copy its ARN, which shows in the lower right corner. The EventBridge rule needs this.
Figure 10 – Finding the CloudWatch alarm ARN
d. Configure EventBridge to consume events from CloudWatch
When the alarm enters the ALARM state, it means it has detected an idle EC2 instance. It will then generate an event that EventBridge can consume and act upon. For this, EventBridge uses rules. EventBridge rules rely on patterns to identify the events and trigger the appropriate actions.
Enter a name and description for the rule. A rule cannot have the same name as another rule in the same Region and on the same event bus.
For Event bus, choose an event bus to associate with this rule. To match events that come from the same account, select AWS default event bus. When an AWS service in the account emits an event, it always goes to the account’s default event bus.
For Rule type, choose Rule with an event pattern.
Select Next.
For Event source, choose AWS services.
Scroll down to Creation method and select Custom pattern (JSON editor).
Enter the following pattern on the Event Pattern
{
  "source": ["aws.cloudwatch"],
  "detail-type": ["CloudWatch Alarm State Change"],
  "detail": {
    "state": {
      "value": ["ALARM"]
    },
    "resources":[
    "<ARN of CW alarms to respond to>"
    ]
  }
}
In the resources element of the pattern, add the ARN of the CloudWatch alarm created for the EC2 instance. The resources element is an array. Add the ARN of every alarm to which this rule monitors and responds. Doing this allows using a single rule to handle the same action for multiple alarms.
Select Next.
Select a target. This is the action that EventBridge executes once it has identified an event. Choose AWS service and select Lambda function.
Select HibernateEC2InstanceFunction.
Select Next.
Add tags to the rule as needed.
Select Next.
Review the rule configuration, and select Create rule.
Figure 11 – EventBridge rule event pattern
Figure 12 – EventBridge rule targets
Testing the implementation
To test the solution, wait for the instance’s CPU utilization to fall below the 10% threshold for 15 minutes. Alternatively, force the alarm to enter the ALARM state with the following AWS CLI command.
Hibernating EC2 instances brings savings during periods of low utilization. Another benefit is that when they start again, they continue their work from where they left off. To hibernate the instance, set the hibernation configuration when launching it. Detect the idle instance with a CloudWatch alarm, and use EventBridge to capture the alarms and trigger a Lambda function to call the Amazon EC2 stop API with the hibernate parameter.
It seems not to be true. Dropbox isn’t sharing all of your documents with OpenAI. But here’s the problem: we don’t trust OpenAI. We don’t trust tech corporations. And—to be fair—corporations in general. We have no reason to.
“OpenAI are training on every piece of data they see, even when they say they aren’t” is the new “Facebook are showing you ads based on overhearing everything you say through your phone’s microphone.”
Willison expands this in a blog post, which I strongly recommend reading in its entirety. His point is that these companies have lost our trust:
Trust is really important. Companies lying about what they do with your privacy is a very serious allegation.
A society where big companies tell blatant lies about how they are handling our data—and get away with it without consequences—is a very unhealthy society.
A key role of government is to prevent this from happening. If OpenAI are training on data that they said they wouldn’t train on, or if Facebook are spying on us through our phone’s microphones, they should be hauled in front of regulators and/or sued into the ground.
If we believe that they are doing this without consequence, and have been getting away with it for years, our intolerance for corporate misbehavior becomes a victim as well. We risk letting companies get away with real misconduct because we incorrectly believed in conspiracy theories.
Privacy is important, and very easily misunderstood. People both overestimate and underestimate what companies are doing, and what’s possible. This isn’t helped by the fact that AI technology means the scope of what’s possible is changing at a rate that’s hard to appreciate even if you’re deeply aware of the space.
If we want to protect our privacy, we need to understand what’s going on. More importantly, we need to be able to trust companies to honestly and clearly explain what they are doing with our data.
On a personal level we risk losing out on useful tools. How many people cancelled their Dropbox accounts in the last 48 hours? How many more turned off that AI toggle, ruling out ever evaluating if those features were useful for them or not?
And while Dropbox is not sending your data to OpenAI today, it could do so tomorrow with a simple change of its terms of service. So could your bank, or credit card company, your phone company, or any other company that owns your data. Any of the tens of thousands of data brokers could be sending your data to train AI models right now, without your knowledge or consent. (At least, in the US. Hooray for the EU and GDPR.)
“Your info won’t be harvested for training” is the new “Your private chatter won’t be used for ads.”
These foundation models want our data. The corporations that have our data want the money. It’s only a matter of time, unless we get serious government privacy regulation.
Lawmakers noted the pharmacies’ policies for releasing medical records in a letter dated Tuesday to the Department of Health and Human Services (HHS) Secretary Xavier Becerra. The letter—signed by Sen. Ron Wyden (D-Ore.), Rep. Pramila Jayapal (D-Wash.), and Rep. Sara Jacobs (D-Calif.)—said their investigation pulled information from briefings with eight big prescription drug suppliers.
They include the seven largest pharmacy chains in the country: CVS Health, Walgreens Boots Alliance, Cigna, Optum Rx, Walmart Stores, Inc., The Kroger Company, and Rite Aid Corporation. The lawmakers also spoke with Amazon Pharmacy.
All eight of the pharmacies said they do not require law enforcement to have a warrant prior to sharing private and sensitive medical records, which can include the prescription drugs a person used or uses and their medical conditions. Instead, all the pharmacies hand over such information with nothing more than a subpoena, which can be issued by government agencies and does not require review or approval by a judge.
Three pharmacies—CVS Health, The Kroger Company, and Rite Aid Corporation—told lawmakers they didn’t even require their pharmacy staff to consult legal professionals before responding to law enforcement requests at pharmacy counters. According to the lawmakers, CVS, Kroger, and Rite Aid said that “their pharmacy staff face extreme pressure to immediately respond to law enforcement demands and, as such, the companies instruct their staff to process those requests in store.”
The rest of the pharmacies—Amazon, Cigna, Optum Rx, Walmart, and Walgreens Boots Alliance—at least require that law enforcement requests be reviewed by legal professionals before pharmacists respond. But, only Amazon said it had a policy of notifying customers of law enforcement demands for pharmacy records unless there were legal prohibitions to doing so, such as a gag order.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


 Buddhike de Silva is a Senior Specialist Solutions Architect at Amazon Web Services. Buddhike helps customers run large scale streaming analytics workloads on AWS and make the best out of their cloud journey.