Post Syndicated from The Atlantic original https://www.youtube.com/shorts/5MSfwrbXVxg
Conditions at Alligator Alcatraz #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/KGQEoZe5Jkk
[$] Bringing the Agama installer to openSUSE Tumbleweed
Post Syndicated from jzb original https://lwn.net/Articles/1107830/
The openSUSE Project has been working on
the Agama installer for four
years; it was the default installer for openSUSE Leap 16.0 when
it was released in 2025, and has been adopted by other openSUSE flavors as
well. Now the project is gearing up to go all-in on Agama for Tumbleweed, the rolling-release
edition that is meant to be where updates and new features land first. Even so,
the community has concerns about losing some of YaST’s legacy functionality and
the impact on installing Tumbleweed on systems that have less RAM.
Beyls: Wrapping up LLVM’s relicensing effort
Post Syndicated from jzb original https://lwn.net/Articles/1108818/
Kristof Beyls has published
a summary to the LLVM discussion forum to announce that the project is
declaring success and bringing its relicensing
effort to a close after eight years.
We’ve been asking past contributors to relicense their work since 2018. New
contributions have come in under Apache-2.0 WITH LLVM-exception since January
19, 2019. Code contributed before that date was under LLVM’s earlier licenses
(UIUC/NCSA, plus MIT for some runtime libraries), so we needed permission from
its authors to move it over. […]Today, more than 99.5% of all lines of code ever contributed to LLVM are
either covered by the new license, too small for copyright to apply, or no
longer in the repository.
Rather than trying to “chase the last tiny fraction forever
” LLVM is
winding up the effort. Any contributors with code contributed before January 19,
2019 who have not signed a relicensing agreement and do not want their
contributions made available under Apache-2.0 with the LLVM-exception can still
reach out to the project to ensure their code has the appropriate SPDX license
identifier.
Vim Classic 8.3.1 released
Post Syndicated from jzb original https://lwn.net/Articles/1108817/
Version
8.3.1 of Vim Classic—a
long-term support fork of Vim maintained without LLM assistance—has been
released.
This release includes applicable Vim patches up to Vim 8.2.3237, including
numerous bug fixes, minor features, and compatibility improvements for Vim
plugins. This release also removes Python 2 support from Vim Classic.
The full list
of changes in this release is available on sourcehut.
Bringing AI education to 300,000 young people across Canada
Post Syndicated from Anna Burton original https://www.raspberrypi.org/blog/bringing-ai-education-to-300000-young-people-across-canada/
We’re pleased to share that we will expand Experience AI across Canada to train 7,000 educators who will reach an estimated 300,000 young people across the country by 2028. This is made possible through our partnerships with Canadian education organisations Actua and Digital Moment, and generously supported by $2 million in funding from Google.org.
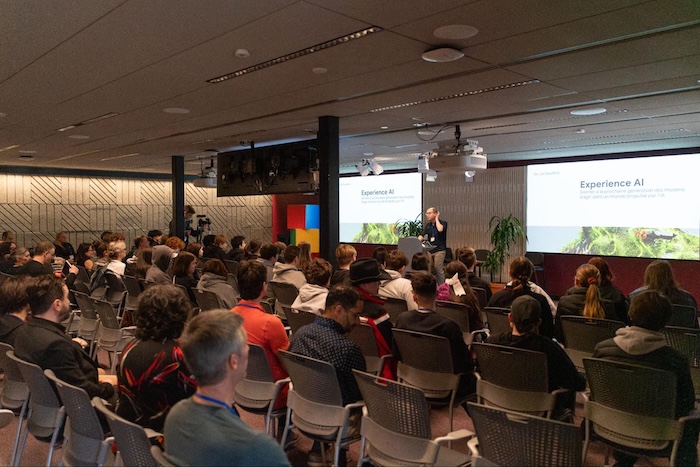
Together with Actua and Digital Moments, we will help young people across Canada develop a foundational understanding of AI technologies, their social and ethical implications, and the role that AI can play in their lives.
AI literacy for young people worldwide through Experience AI
Everyday activities such as finding information, working, and solving problems are now linked with AI systems at many points. We think that all young people need more than access to AI tools and the ability to use them: they need the knowledge, skills, and confidence to understand how AI works, to think critically about its use and impact, and to create their own AI-based solutions.
Experience AI, developed in partnership with Google DeepMind, is a free educational programme that helps teachers and students learn about artificial intelligence (AI). It introduces young people to how AI systems work and how they are used in everyday contexts through lessons, classroom resources, and hands-on activities. The resources give young people opportunities to think critically about the role of AI in society.
We bring AI literacy to young people across the world with Experience AI by building trusted partnerships with local organisations that lead sustainable delivery of the programme in ways that suit their contexts. Through this global network of over 40 Experience AI partners, we have trained over 63,000 educators who can reach an estimated 6 million young people. Today, Experience AI resources are used in over 195 countries and available in over 22 languages and localised versions.
In 2025, in recognition of its global impact, Experience AI was named a laureate of the UNESCO King Hamad Bin Isa Al-Khalifa Prize for the Use of ICT in Education.
Reaching communities across Canada through partnerships
Canada, the second largest country in the world by area, is home to a diverse range of communities, languages, and educational settings. Working to make AI education accessible to all young people across such a vast country means supporting these differences by working with local partners who understand the needs of their communities.
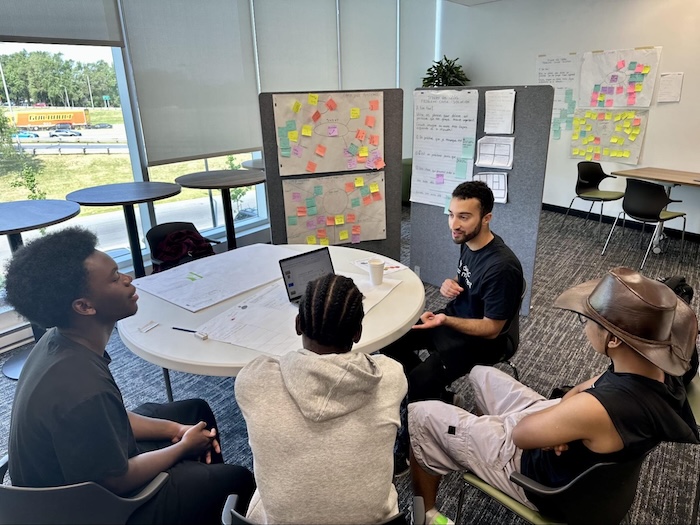
In 2023 we tested the Experience AI training with Canadian teachers, already in partnership with Digital Moment. Through this training we reached 500 educators and an estimated 56,000 young people.
In this new phase of bringing Experience AI to Canada, we’re delighted to build on our relationship with Digital Moment, and to develop a new partnership with Actua. Both organisations have extensive experience of delivering STEM, digital skills, and AI education initiatives to Canadian classrooms and communities. Together we will support thousands of Canadian teachers with free training, resources, and support that will enable them to bring high-quality AI education to the young people in their classrooms.
Indra Kubicek, CEO of Digital Moment, shared:
“We’re excited to continue our partnership with the Raspberry Pi Foundation and build on our experience bringing Experience AI to educators across Canada. Together, we have an opportunity to expand access to trusted, practical classroom resources that give educators the knowledge and confidence to help young people understand AI, think critically about its impact, and make informed choices about its role in their lives. We look forward to reaching more educators and students across Canada and helping build a strong foundation for AI literacy that puts people, learning, and human values at the centre.”
Jennifer Flanagan, CEO of Actua, explained:
“For more than 25 years, Actua has helped tens of thousands of educators and millions of young Canadians build the skills and confidence to navigate a changing world. AI is changing that world faster than ever, and we need to make sure teachers and students are prepared. Through Experience AI, we’re helping educators bring AI literacy into their classrooms and give youth the knowledge to understand this technology, the confidence to question it, and the skills to help shape its future.”
Helping young people shape their digital future
All young people need opportunities to develop the skills, knowledge, and confidence to navigate and shape a world where AI technologies are widely used. With support from Google.org and in partnership with Actua and Digital Moment, we’re excited to make AI education accessible to more young people across Canada.
Explore Experience AI and discover the free educational resources at experience-ai.org.
The post Bringing AI education to 300,000 young people across Canada appeared first on Raspberry Pi Foundation.
Security updates for Friday
Post Syndicated from jzb original https://lwn.net/Articles/1108811/
Security updates have been issued by AlmaLinux (bind9.18, bubblewrap, fence-agents, freerdp, grafana, grafana-pcp, gstreamer1-plugins-bad-free, jackson-core, jackson-databind, java-17-openjdk, java-21-openjdk, java-25-openjdk, kernel, kernel-rt, mysql8.4, mysql:8.4, qt5-qtbase, qt5-qtdeclarative, raptor2, resteasy, and sos), Debian (electrum, nginx, openjdk-17, pam-mysql, php8.2, and php8.4), Fedora (aws, bind9-next, blender, c-ares, composer, dr_libs, et, gh, incron, libaec, libfontenc, libXfont2, mtools, nebula, perl-Imager, perl-Text-JSCalendar, perl-Text-JSContact, php, python-loguru, python3.6, qpid-proton, roundcubemail, runc, and xen), Gentoo (nginx, PHP, and Ruby), Mageia (hplip), Oracle (.NET 10.0, .NET 11.0, .NET 8.0, .NET 9.0, bubblewrap, emacs, firefox, flatpak-builder, gcc, gimp, glibc, grafana, grafana-pcp, gstreamer1, gvfs, java-1.8.0-openjdk, java-17-openjdk, java-21-openjdk, java-25-openjdk, libssh2, mod_http2, perl-CGI, perl-DBI, perl-DBI:1.641, python3.9, rpm, squid, tesseract, thunderbird, tigervnc, util-linux, webkit2gtk3, and xdg-dbus-proxy), Red Hat (compat-openssl10, kernel, nginx, nginx:1.24, nginx:1.26, nodejs22, nodejs:22, openssl, python-urllib3, python3.12-urllib3, qt5-qtbase, and qt6-qtbase), Slackware (gnutls, perl, and php), SUSE (cifs-utils, elemental-operator, elemental-system-agent, elemental- toolkit, haproxy, java-11-openjdk, kernel, libXi, python-M2Crypto, python-oauthlib, rekor, and xen), and Ubuntu (kernel, linux, linux-aws, linux-aws-5.4, linux-azure, linux-bluefield, linux-fips, linux-gcp, linux-gcp-5.4, linux-gcp-fips, linux-hwe-5.4, linux-ibm, linux-ibm-5.4, linux-iot, linux-kvm, linux-oracle, linux-raspi, linux-raspi-5.4, linux-xilinx-zynqmp, linux, linux-aws, linux-aws-fips, linux-aws-hwe, linux-azure, linux-azure-4.15, linux-azure-fips, linux-fips, linux-gcp, linux-gcp-4.15, linux-gcp-fips, linux-hwe, linux-kvm, linux-oracle, linux, linux-aws, linux-aws-fips, linux-gcp, linux-gcp-6.8, linux-gke, linux-gkeop, linux-ibm, linux-ibm-6.8, linux-oracle-6.8, linux-vmware, linux, linux-aws, linux-fips, linux-kvm, linux-lts-xenial, linux, linux-aws, linux-gcp, linux-gcp-5.15, linux-gke, linux-gkeop, linux-ibm, linux-ibm-5.15, linux-oracle, linux, linux-aws, linux-gcp, linux-gcp-7.0, linux-gke, linux-ibm, linux-oem-7.0, linux-vmware, linux-aws-5.15, linux-aws-fips, linux-aws-fips, linux-kvm, linux-fips, linux-gcp-fips, linux-gcp-fips, linux-oracle, nginx, openjdk-17-crac, openjdk-21-crac, openjdk-25-crac, openjdk-8, pyjwt, and ruby3.3, ruby3.2, ruby3.0).
Hippo Farming in America
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=1tfsg0a0SYs
Opening a 400-Year-Old Cryptex
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/11/opening-a-400-year-old-cryptex.html
Researchers used CT scanning technology to recover the code and open a 400-year-old cryptex padlock.
You can buy a USB-drive cryptex.
Йотова, Йотова, обади се!
Post Syndicated from Емилия Милчева original https://www.toest.bg/yotova-yotova-obadi-se/
Има ли България президент на борда? Да произнесе слово на поклонението на Вежди Рашидов, да връчи отличия на офицери и да поздрави Сухопътните войски за празника им би могъл и актьор, повикан по заместване.
Илияна Йотова спечели балотажа, за да върши същото. Когато е наложително да каже нещо извън протокола, настъпва антракт.
Йотова ли спечели, или Гюров загуби?
На президентския балотаж страхът от война победи обещанието за промяна. Емилия Милчева анализира как управляващите превърнаха мира в предизборно оръжие, защо Андрей Гюров не успя да наложи собствен дневен ред и какво политическо бъдеще очаква двамата кандидати след изборите.
От президента се очаква да задава на управляващите въпроси, които те предпочитат да подминат. За тази цел има вето, но понякога е достатъчно да вземе думата, докато решението още може да се промени. Йотова имаше такъв повод още в първите дни след балотажа, когато депутати от управляващата „Прогресивна България“ предложиха да орежат трудовите права за личните асистенти в Закона за личната помощ.
Мълча за майките
Миналата година Йотова имаше да каже доста повече. Като вицепрезидент тя обвини кабинета „Желязков“, че прокарва бюджета за 2026 г. без диалог и с „безпрецедентно арогантно отношение на властта“. И Георги Първанов навремето се намеси в дебата за бюджет 2005. Той предупреди, че може да наложи вето заради текстове, които променят правилата за интеграция на хората с увреждания.
През 2020 г., когато изведоха майките от „Системата ни убива“ от парламента, Йотова попита защо председателката на 44-тото Народно събрание Цвета Караянчева не е отишла да разговаря с тях. Тя каза тогава, че на „Дондуков“ 2 гражданите могат да се срещнат с нея всеки ден.
Шест години по-късно въпросът ѝ към Караянчева става въпрос към самата нея.
Проектът предвиждаше трудовите договори на личните асистенти да бъдат заменени с друг вид договори, да отпадне добавката за прослужено време, а заплащането им вече да не е обвързано с минималната заплата. За майките, които са лични асистенти на децата си, това означаваше да загубят трудови права именно за работата, която им позволява да се грижат за тях. Цинично прозвуча и коментарът от „Прогресивна България“, че така им освобождават възможност да работят на още едно място.
Майките обявиха готовност за протест и на 13 ноември, три дни след внасянето на проекта, управляващите го оттеглиха. През тези три дни от „Дондуков“ 2 не се чу нито една дума от първата жена, заела президентския пост, а също майка и баба.
Имаме си президентка. Съвсем
Светла Енчева коментира избора на първата жена президент на България. Йотова дължи възможността да заеме този пост на борбата за равноправие, но не е защитавала особено правата на жените. А след 10 години в сянката на Румен Радев тепърва ще трябва да доказва политическата си самостоятелност.
Съвсем различна беше Йотова по време на кампанията. „Първата ни задача е да се погрижим за най-бедните и уязвимите“, каза тя в Перник шест дни преди първия тур.
За личната помощ Йотова замълча, а преди това замълча и за смъртта по пътищата. Единственото, което направи след тежката верижна катастрофа на магистрала „Тракия“, в която живота си загубиха 13 души, а десетки пострадаха, беше да прекъсне участието си в Парижкия форум за мир и да изрази съболезнования.
Какво поиска от институциите, които отговарят за безопасността по пътищата? Нищо – защото за това се иска да заемеш позиция, но изглежда, че Илияна Йотова не се осмелява да надигне глас пред управляващите от партия „Прогресивна България“, подкрепила я за президентския пост.
Проговори за кратко
На 16 ноември в Пномпен, където представляваше България на Срещата на върха на франкофонията, Йотова представи изводите от дискусия за предотвратяването и уреждането на конфликти. Същия ден в българската изключителна икономическа зона беше ударен товарният кораб BETUL 8, пълен с украинска пшеница, а след него и газовоз. От „Демократична България“ преброиха седем потопени плавателни съда в изключителната икономическа зона на България и настояха Йотова да свика Консултативния съвет за национална сигурност (КСНС).
Патриоти за мъртвите – страхливци за живите
Два кораба потънаха край България, а на повърхността изплува фактът, че пак не знаем какво е станало. Докато институциите внимателно подбират условното наклонение и каканижат с „да биха били…, щяхме и ние…“, миналото напомня, че руските следи у нас не са нито нови, нито малко. От Емилия Милчева.
След честването на празника на Сухопътните войски край Гургулят на 19 ноември Йотова обясни пред журналисти защо няма да свика отново КСНС за Черно море. Според нея първо трябва да се изпълнят решенията от заседанието на 7 октомври. Като свършена работа тя посочи срещата на министрите на отбраната на България, Румъния и Турция и изтъкна дейността на общата противоминна група, чиито задачи вече включват и спасителни операции.
За останалите мерки Йотова каза, че очаква правителството и парламентарното мнозинство да ги изпълнят в следващите дни. Готова е да изслуша мотивите на опозицията, но досега е чула призива ѝ само през медиите и не е получила официално писмо.
В същия ден и премиерът Румен Радев призова шестте черноморски държави да се договорят за спиране на атаките срещу цивилни кораби. Йотова отиде по-далеч и заговори за мораториум върху бойните действия в целия басейн. А как България ще пази корабите дотогава? Няма как, разбра се от отговора на министър-председателя:
И аз искам да унищожаваме дроновете, но няма как към момента по чисто военнотехнически причини.
След като в изборната нощ президентката каза, че българите са избрали мира, можеше от висотата на позицията си да попита какво става с разследването за произхода на дроновете. Защото дори руският президент Путин призна, че Кремъл стои зад атаките с безпилотни летателни апарати, но не и българските управляващи.
Те започнаха да удрят нашите танкери в Черно море. В отговор, както всички знаят, ние започнахме да действаме по същия начин.
Попитана как евентуални доказателства за руски произход на дроновете биха се отразили на отношенията с Москва, Йотова обясни, че според нея Русия не се опитва да превърне България в част от войната. Тези разсъждения не носят особена полза на екипажите, които трябва да знаят кой се грижи за тяхната сигурност при плаването през вътрешното море. Черно море вече е опасен търговски маршрут, а през неговите пристанища минава около 14% от зърното, превозвано по море в света, по оценка на международната корабоплавателна асоциация BIMCO от август 2026 г.
Страдателният залог на генерал-премиера
„Онзи-който-не-бива-да-се-назовава“ продължава да потапя кораби в Черно море. Междувременно Румъния сваля дронове и укрепва отбраната си, а ние търсим доказателства и призоваваме безадресно за мораториуми. Колко струва снишаването, когато войната вече е на брега ни? От Емилия Милчева.
Ами Комисията по досиетата?
За КСНС за ударите в Черно море Йотова каза, че не е получила официално писмо. По друг въпрос обаче президентката е сред адресатите на отворено писмо. Над сто общественици поискаха от премиера Румен Радев да оттегли проекта за закриване на Комисията по досиетата и изпратиха копие до Йотова и до председателката на Народното събрание. А над 4500 души са подписали онлайн петицията със същото искане.
Проектът прехвърля функциите на Комисията към Държавна агенция „Архиви“. Сред публикуваните становища от общественото обсъждане няма нито едно в подкрепа на закриването. Къде стои президентката по въпроса? Може да вземе думата още сега, докато има шанс проектът да бъде оттеглен. Но тя е избрала сурово да мълчи.
Проектът за закриване на Комисията по досиетата тръгна от параграф 8 на бюджет 2026, който Йотова обнародва през юли. Това е обяснение за мълчанието, защото на практика е съучаствала в затварянето на архивите на бившите тайни служби.
Когато парламентът приеме бюджет 2027, Йотова ще трябва да реши дали да подпише указа за обнародването му, или да го върне за ново обсъждане. От ГЕРБ вече предупредиха, че ще поискат вето, ако държавните разходи за догодина бъдат приети в този си вид.
От юли България е в процедура при прекомерен дефицит, а в бюджет 2027 кабинетът на Радев залага дефицит от 4,2% от БВП на начислена основа и иска да поеме до 8,6 млрд. евро нов дълг. Това означава, че държавата планира бюджетен дефицит над допустимите по европейските правила 3% от БВП, въпреки че вече е под наблюдението на Европейската комисия и трябва да предприема мерки за ограничаването му. През 2013 г. президентът Росен Плевнелиев върна текстове от актуализацията на бюджета и поиска кабинетът „Орешарски“ да каже за какво ще похарчи новия дълг.
От обяснения на вицепремиера и министър на финансите Гълъб Донев стана ясно, че около 2,1 млрд. евро са нужни за погасяване на стари задължения с настъпващ падеж. Йотова има какво да попита кабинета на Радев – за какво е предвиден останалият ресурс в година на местни избори.
По какви критерии кабинетът ще определя кои общински проекти да финансира и кога да плати по тях? Отговорът на този въпрос се чака от регионалния министър Иван Шишков, чието министерство ще разполага с 2,51 млрд. евро, а проектите (и кметовете) се пресяват чрез обиколките по инициативата „Регионите говорят“.
Пак по време на кампанията Илияна Йотова говореше за „синхрон между институциите и за взаимен коректив“. Тя е избрала да бъде президентският статист на Радев.
На 31 декември микрофонът ще е неин. Дотогава може да зададе поне един въпрос на управляващите.
Холи Бери е в менопауза. И сега какво?
Post Syndicated from Надежда Цекулова original https://www.toest.bg/halle-berry-e-v-menopauza-i-sega-kakvo/
/* ==========================================================================
„Анатомия на пола: Менопауза“ — ефекти при скрол за ТАЗИ статия
Зарежда се в началото на статията (Post → Code injection → Header).
Работи заедно с menopause.js. Не пипа стиловете на темата: всичко е
закачено за data-fx атрибути и класове с префикс mx-.
========================================================================== */
:root{
/* „топлина“ палитра на проекта */
–mx-red:#dc1010; –mx-lime:#c2d910; –mx-amber:#ecb716;
–mx-teal:#0e8da3; –mx-blue:#042da6; –mx-maroon:#600202;
–mx-ink:var(–black, hsl(220,5%,12%));
–mx-mute:var(–grey, hsl(210,3%,63%));
}
/* ———- лента за четене: същата
/* ==========================================================================
„Анатомия на пола: Менопауза“ — ефекти при скрол за ТАЗИ статия
Зарежда се в края на статията (Post → Code injection → Footer) или с defer.
Работи с menopause.css. Търси елементи с data-fx=”…” и .mx-ig в текста.
Ефектите се намират по ТЕКСТ (виж списъка FX вътре) — не е нужно HTML в параграфите.
Не променя нищо друго на страницата.
Ефекти (слагат се ръчно в HTML-а на статията):
data-fx=”pop” думите подскачат една по една при стигане до тях
data-fx=”not” от нормален към най-дебелия шрифт
data-fx=”blur” от размазано към рязко
data-fx=”reveal” думите се проявяват; получава жълт маркер
data-fx=”grow” уголемява се
data-fx=”scatter” думата „избухва“ в букви
data-fx=”boldup” удебелява се
data-fx=”shimmer” топлинен спектър минава през думата
data-fx=”redsweep” думите стават червени една по една
.mx-ig инфографика с точки (виж snippets.html)
========================================================================== */
(function(){
‘use strict’;
function init(){
var root = document.documentElement;
var reduce = window.matchMedia && window.matchMedia(‘(prefers-reduced-motion: reduce)’).matches;
function $$(s){ return Array.prototype.slice.call(document.querySelectorAll(s)); }
var HEAT = [‘#dc1010′,’#ecb716′,’#c2d910′,’#0e8da3′,’#042da6′,’#600202’];
var PAL = [[4,45,166],[14,141,163],[194,217,16],[236,183,22],[220,16,16],[96,2,2]];
function pal(x){
x = Math.min(1, Math.max(0, x)) * (PAL.length-1);
var i = Math.min(PAL.length-2, Math.floor(x)), f = x – i, a = PAL[i], b = PAL[i+1];
return ‘rgb(‘ + [0,1,2].map(function(k){ return Math.round(a[k] + (b[k]-a[k])*f); }).join(‘,’) + ‘)’;
}
/* ==========================================================================
КАКВО КЪДЕ СЕ СЛУЧВА — тук се определят ефектите, текстът в Ghost остава обикновен.
fx — ефектът (pop, not, blur, reveal, grow, scatter, boldup, shimmer, redsweep)
find — фразата в текста (интервалите са без значение)
wrap — по желание: само част от find да получи ефекта (напр. само „не“)
target — по желание: слагане върху целия елемент, напр. ‘h4′ (за reveal и redsweep)
mark — по желание, за reveal: част от find, която получава жълт маркер
Ако фраза не се намери, в конзолата излиза предупреждение „[mx] не е намерена“.
========================================================================== */
/* ЗАКЪСНЕНИЕ: колко по-късно да започват ефектите при скрол (0.12 = 12% от височината на екрана).
По-голямо число = ефектите се пускат, когато текстът е по-високо на екрана. 0 = без закъснение. */
var DELAY = .12;
var FX = [
{fx:’pop’, find:’слаби, красиви, млади и успешни’},
{fx:’not’, find:’изследванията не потвърдили’, wrap:’не’},
{fx:’blur’, find:’„просто остарявам“’},
{fx:’blur’, find:’„това се случва на всички жени“’},
{fx:’reveal’, find:’„И тази се опитва да ни продаде остаряването“’, target:’h4′, mark:’продаде остаряването’},
{fx:’grow’, find:’„Аз съм в менопауза“,’},
{fx:’scatter’, find:’избухна’},
{fx:’boldup’, find:’без изключение са част от маркетингова стратегия’},
{fx:’shimmer’, find:’лонджевити’},
{fx:’redsweep’, find:’окей, вече ни е социално разрешено да остаряваме, но само ако не ни личи.’, target:’h4′}
];
function escRe(s){ return s.replace(/[.*+?^${}()|[\]\\]/g, ‘\\$&’); }
function findRange(root, phrase){
var re = new RegExp(phrase.split(/\s+/).map(escRe).join(‘\\s+’));
var w = document.createTreeWalker(root, NodeFilter.SHOW_TEXT, {acceptNode:function(n){
var p = n.parentNode && n.parentNode.nodeName;
if(p === ‘SCRIPT’ || p === ‘STYLE’) return NodeFilter.FILTER_REJECT;
if(n.parentNode.closest && n.parentNode.closest(‘.mx-assets,[data-fx],.mx-ig-wrap’)) return NodeFilter.FILTER_REJECT;
return NodeFilter.FILTER_ACCEPT;
}});
var n;
while((n = w.nextNode())){
var m = re.exec(n.nodeValue);
if(m){ var r = document.createRange(); r.setStart(n, m.index); r.setEnd(n, m.index + m[0].length); return r; }
}
return null;
}
function wrapRange(r, attrs){
var span = document.createElement(‘span’);
Object.keys(attrs).forEach(function(k){ span.setAttribute(k, attrs[k]); });
r.surroundContents(span);
return span;
}
function autoFx(){
var root = document.querySelector(‘.post-content’) || document.body;
FX.forEach(function(spec){
var r = findRange(root, spec.find);
if(!r){ console.warn(‘[mx] не е намерена фраза:’, spec.find); return; }
if(spec.target){
var el = r.startContainer.parentNode.closest(spec.target);
if(!el){ console.warn(‘[mx] няма’, spec.target, ‘около:’, spec.find); return; }
if(spec.mark){
var mr = findRange(el, spec.mark);
if(mr) wrapRange(mr, {‘class’:’mx-mk’});
}
el.setAttribute(‘data-fx’, spec.fx);
return;
}
if(spec.wrap){
var rel = new RegExp(escRe(spec.wrap));
var txt = r.toString(), at = txt.search(rel);
if(at 10 ? 0 : .62);
var to = el.hasAttribute(‘data-heat-to’) ? +el.getAttribute(‘data-heat-to’) : (total > 10 ? 1 : from + .1*(total-1));
for(var i=0;i 1 ? i/(total-1) : 0));
f.style.setProperty(‘–c’, f._col);
grid.appendChild(f); figs.push(f);
}
return {el:el, total:total, target:target, figs:figs, val:el.querySelector(‘.mx-ig-val’), fmt:el.getAttribute(‘data-fmt’) || ‘int’, top:0, a:.85 – DELAY, b:.4 – DELAY};
});
function applyIG(o, p){
var k = o.target * p;
o.figs.forEach(function(f, j){
var part = o.total 0 ? 1 : 0) : Math.min(1, Math.max(0, k – j)); // малките редове (1 от 5) се пълнят цели
var s = (part * 100).toFixed(0) + ‘%’;
if(f._s !== s){ f.style.setProperty(‘–f’, s); f._s = s; }
});
var last = o.figs[Math.max(0, Math.ceil(k) – 1)];
o.el.style.setProperty(‘–nc’, last ? last._col : ‘inherit’);
if(o.val) o.val.textContent = o.fmt === ‘dec’ ? k.toFixed(1).replace(‘.’, ‘,’) : String(Math.round(k));
}
/* ———- без анимации ———- */
if(reduce){
root.classList.add(‘mx-static’);
igs.forEach(function(o){ applyIG(o, 1); });
return;
}
root.classList.add(‘mx-js’);
$$(‘[data-fx=”pop”],[data-fx=”blur”]’).forEach(function(el){ splitDeep(el, {i:0}); });
/* ———- 1) еднократни: pop ———- */
var io = new IntersectionObserver(function(entries){
entries.forEach(function(en){
if(en.isIntersecting) en.target.classList.add(‘mx-in’);
else en.target.classList.remove(‘mx-in’); // пуска се пак при следващо стигане
});
}, {rootMargin:’-10% 0px -‘ + Math.round(28 + DELAY*100) + ‘% 0px’, threshold:0});
$$(‘[data-fx=”pop”]’).forEach(function(e){ io.observe(e); });
/* ———- 2) избухване ———- */
var bursts = $$(‘[data-fx=”scatter”]’);
var ALPHA = ‘абвгдежзиклмнопрстуфхцчшюяАБВГДЕЖЗИКЛМНОПРСТ’;
function burst(el){
el.classList.add(‘mx-in’);
var word = el.textContent.replace(/\s/g,”), n = 44;
var spread = Math.min(1, window.innerWidth/900);
for(var i=0;i<n;i++){
var s = document.createElement('span'); s.className = 'mx-pt';
s.textContent = Math.random() < .5 ? word.charAt(Math.floor(Math.random()*word.length)) : ALPHA.charAt(Math.floor(Math.random()*ALPHA.length));
s.style.left = (Math.random()*100) + '%';
s.style.fontSize = (.8 + Math.random()*1.5).toFixed(2) + 'em';
s.style.color = HEAT[Math.floor(Math.random()*HEAT.length)];
el.appendChild(s);
var a = Math.random()*Math.PI*2, d = (70 + Math.random()*170)*spread;
var dx = Math.cos(a)*d*1.35, dy = Math.sin(a)*d*.85, rot = Math.round(Math.random()*240 – 120);
var anim = s.animate([
{transform:'translate(-50%,-50%) scale(.2) rotate(0deg)', opacity:0},
{transform:'translate(calc(-50% + '+(dx*.35).toFixed(0)+'px),calc(-50% + '+(dy*.35).toFixed(0)+'px)) scale(1.1) rotate('+(rot*.4)+'deg)', opacity:1, offset:.18},
{transform:'translate(calc(-50% + '+dx.toFixed(0)+'px),calc(-50% + '+dy.toFixed(0)+'px)) scale(.9) rotate('+rot+'deg)', opacity:0}
], {duration:1000 + Math.random()*900, delay:Math.random()*140, easing:'cubic-bezier(.12,.75,.3,1)', fill:'forwards'});
anim.onfinish = (function(node){ return function(){ node.remove(); }; })(s);
}
}
var ioB = new IntersectionObserver(function(entries){
entries.forEach(function(en){
var el = en.target;
if(en.isIntersecting){
if(el._armed === false) return;
el._armed = false;
setTimeout(function(){ burst(el); }, 450);
} else { el._armed = true; el.classList.remove('mx-in'); }
});
}, {rootMargin:'-32% 0px -' + Math.round(32 + DELAY*100) + '% 0px', threshold:0});
bursts.forEach(function(e){ ioB.observe(e); });
/* ———- 3) вързани за скрола ———- */
var cfg = { grow:[.85,.45], boldup:[.85,.45], redsweep:[.85,.4], blur:[.95,.5], not:[.85,.5], shimmer:[.9,.3], reveal:[.85,.45] };
var linked = $$('[data-fx="grow"],[data-fx="boldup"],[data-fx="shimmer"],[data-fx="redsweep"],[data-fx="blur"],[data-fx="not"],[data-fx="reveal"]').map(function(el){
var type = el.getAttribute('data-fx'), o = {el:el, type:type, a:cfg[type][0] – DELAY, b:cfg[type][1] – DELAY, top:0, last:-1};
if(type === 'redsweep'){ o.n = splitDeep(el, {i:0}); o.words = Array.prototype.slice.call(el.querySelectorAll('.mx-w')); }
if(type === 'reveal'){ o.n = splitDeep(el, {i:0}); o.words = Array.prototype.slice.call(el.querySelectorAll('.mx-w')); o.mk = el.querySelector('.mx-mk'); }
if(type === 'blur'){ o.words = Array.prototype.slice.call(el.querySelectorAll('.mx-w')); o.n = o.words.length; }
return o;
});
function ease(p){ return p*p*(3-2*p); }
function apply(o, p){
if(o.type === 'reveal'){
var kr = Math.round(p*o.n);
if(kr !== o.last){ o.words.forEach(function(w,i){ w.classList.toggle('mx-on', i = .98);
} else if(o.type === ‘redsweep’){
var k = Math.round(p*o.n);
if(k !== o.last){ o.words.forEach(function(w,i){ w.classList.toggle(‘mx-hot’, i < k); }); o.last = k; }
} else if(o.type === 'blur'){
var spread = .6;
o.words.forEach(function(w,i){
var q = Math.min(1, Math.max(0, p*(1+spread) – (i/Math.max(1,o.n-1))*spread));
w.style.setProperty('–b', (1-ease(q)).toFixed(3));
});
} else if(o.type === 'not'){
var s = p < .25 ? 0 : p < .5 ? 1 : p < .75 ? 2 : 3;
if(s !== o.last){ o.el.setAttribute('data-w', s); o.last = s; }
} else {
o.el.style.setProperty('–p', ease(p).toFixed(4));
}
}
function measure(){
// позицията се мери при изключен ефект, за да няма обратна връзка с layout-а
linked.forEach(function(o){
if(o.type==='not'){ o.el.setAttribute('data-w',0); o.last=0; }
else if(o.type==='blur'){ o.words.forEach(function(w){ w.style.setProperty('–b',1); }); }
else if(o.type!=='redsweep' && o.type!=='reveal'){ o.el.style.setProperty('–p', 0); }
});
linked.forEach(function(o){ o.top = o.el.getBoundingClientRect().top + window.scrollY; });
igs.forEach(function(o){ o.top = o.el.getBoundingClientRect().top + window.scrollY; });
update();
}
function update(){
var vh = window.innerHeight, y = window.scrollY;
linked.forEach(function(o){
apply(o, Math.min(1, Math.max(0, (y + vh*o.a – o.top) / (vh*(o.a-o.b)))));
});
igs.forEach(function(o){
applyIG(o, Math.min(1, Math.max(0, (y + vh*o.a – o.top) / (vh*(o.a-o.b)))));
});
}
var tick = false;
window.addEventListener('scroll', function(){ if(tick) return; tick = true; requestAnimationFrame(function(){ tick = false; update(); }); }, {passive:true});
window.addEventListener('resize', measure);
window.addEventListener('load', measure);
measure();
/* помощни функции за преглед/тест */
window.mxShow = function(on){ root.classList.toggle('mx-show', !!on); };
window.mxReplay = function(){
$$('[data-fx].mx-in').forEach(function(e){ e.classList.remove('mx-in'); });
window.scrollTo({top:0, behavior:'smooth'});
setTimeout(function(){ bursts.forEach(function(e){ e._armed = true; }); }, 700);
};
}
if(document.readyState === 'loading') document.addEventListener('DOMContentLoaded', init);
else init();
})();
Всички жени, които говорят публично за менопаузата, изглеждат слаби, красиви, млади и успешни. Или поне аз само такива намерих. Това със сигурност е добра стратегия за „ребрандиране“ на менопаузата (фразата е на Холи Бери, за нея – малко по-долу), но какво си мисли жената, която не се е появявала на корица на списание, когато се погледне в огледалото и нищо в тялото ѝ не функционира както преди?
Когато си жената котка, дори менопаузата ти стои секси.
Холи Бери, американската актриса, изиграла жената котка в едноименния филм и още десетки роли, които са я направили разпознаваема в целия свят, стана едно от най-популярните лица на менопаузата, разказа за целия си преход към нея, създаде около него мащабен бизнес, написа законопроект и взе на абордаж няколко американски медицински университета.
Започвам този текст с нейната история, защото е много ярък (и секси) пример, върху който да поразсъждаваме за границата между маркетинга и работата в обществена полза в контекста на една дълго (в смисъл хилядолетия) неглижирана здравна тема като менопаузата. Маркетингът не е задължително нещо лошо, напротив – създава възможност да се предложи информация там, където публичните политики никакви ги няма (например в здравното образование).
Остава обаче впечатлението, че всеки, който говори по една от най-важните теми за съвременната жена, се опитва да ѝ продаде нещо. А понякога имаме нужда просто някой да ни избърше сълзите, да ни каже, че петте кила отгоре много ни отиват, и да ни предпише вагинален естроген (но за него – в друг текст).
Холи Бери има дълга и изцяло публична история със симптомите на преходната възраст, която започва, когато актрисата е на 54 г.
Тя разказва публично, как потърсила помощ заради силна болка след секс и получила диагноза „херпес“, която изследванията не потвърдили. Оказало се, че симптомите са свързани с перименопаузата. Потвърждаването на това обаче отнело време, защото дори лекарят ѝ в началото се смущавал да спомене думата „менопауза“ пред нея, разказва Бери в страницата на инициативата си Re-spin.
„Лекарите ми казваха, че „просто остарявам“ и че „това се случва на всички жени“, продължава актрисата. Тя споделя, че когато най-после стига до специалист по менопаузата, е толкова объркана и неподготвена, че дори не знае какви въпроси да му зададе, давайки си сметка, че щом тя, световноизвестна актриса, носителка на „Оскар“, кралица на красотата, жена с множество успешни инициативи и влияние, се чувства така, то как ли се чувстват жените от по-непривилегировани социални групи?
Водена от фрустрацията си, през 2020 г. Бери създава платформата Re-spin – първоначално като място, на което жените могат да получат насоки и основана на науката информация. През 2025 г. инициативата се ребрандира като „услуга на едно гише“ за жени в перименопауза и менопауза с амбицията да им предложи всичко необходимо.
„И тази се опитва да ни продаде остаряването“,
ще си кажете и ще е обяснимо, защото това е усещането напоследък. Но за Холи няма да сте напълно прави. Наред с бизнеса си актрисата развива мащабна застъпническа дейност. През 2024 г. застава на емблематичния за САЩ хълм Капитолия редом до група сенаторки както от Демократическата, така и от Републиканската партия, за да представят законопроект за по-добри грижи за жените на средна възраст.
„Аз съм в менопауза“,
обявява тя пред журналистите и това явно е толкова впечатляващо, че го отразяват дори български медии.
Законопроектът все още не е гласуван, но Бери продължава да говори публично за нуждата от него, като паралелно работи и за промяна на обучителните програми в медицинските университети, така че бъдещите лекари да знаят по-добре какво се случва с жените в перименопауза и менопауза и как да им осигурят адекватни грижи.
Че има нужда от такава промяна, доказват и данните. В проучване, публикувано през 2019 г. в Mayo Clinic Proceedings, са анкетирани 183 лекари, специализиращи обща медицина, вътрешни болести и акушерство и гинекология в 20 програми в САЩ. Близо 94% от отговорилите на съответния въпрос смятат обучението за грижи при менопауза за важно или много важно, но едва 6,8% се чувстват достатъчно подготвени, а всеки пети съобщава, че по време на специализацията си не е имал нито една лекция по темата.
Проучване сред 183 лекари от 20 програми за специализация в САЩ.
94%
смятат обучението за грижи при менопауза за важно или много важно
6,8%
се чувстват достатъчно подготвени
1 от всеки 5
не е имал нито една лекция по темата по време на специализацията си
Сред пионерите в открития публичен разговор за менопаузата е и Анджелина Джоли, която шокира не само феновете си, когато премахна млечните си жлези и яйчниците си, за да се предпази от развитие на онкологични заболявания. Това стана през 2013–2015 г. и актрисата коментираше спокойно, открито и в детайли както решенията си за превантивните операции, така и последиците от тях, сред които и настъпилата вследствие на интервенциите менопауза.
В последните няколко години обаче темата буквално избухна и сякаш внезапно се оказа, че десетки публично известни жени имат какво да ни кажат за прехода си към живот в репродуктивно неактивна възраст, и са готови да вложат усилия за по-адекватни публични политики в държавите си.
Менопаузата: Упътване за употреба
Менопаузата е навсякъде, а ние се лутаме между научни знания, клишета и обещания за вечна младост. В първия текст от новата ни поредица Надежда Цекулова тръгва от своя опит, за да потърси какво знаем за този период, защо засяга всички и как да се ориентираме сред съветите, симптомите и маркетинга.
В Съединените щати и Обединеното кралство като че ли разговорите достигат до най-широка аудитория и дори и до нас – някои от следваните и от жени в България лекарки инфлуенсърки по темата, като д-р Мери Клер Хейвър, д-р Луиз Нюсън, д-р Рина Малик, са далеч от представата ни за скучен човек в бяла престилка и доста по-близо до образа на „селебрити“ (личност, която вече е толкова известна, че дори не помним защо точно е известна). В разговора за остаряването и последиците от него се включват Опра Уинфри, Наоми Уотс, Мишел Обама, Ема Томпсън… И всъщност мога да продължа така, изброявайки имена, до края на текста.
Вълната залива целия свят
Макар у нас да не сме чували за част от активистките за по-адекватна информация и грижи за жените в перименопауза и менопауза, много от тях са истински звезди в своите държави. В Шотландия например олимпийската шампионка по бягане с препятствия Сали Гънъл стана лице на кампания, която цели да мотивира спортните клубове да адаптират тренировъчните си програми така, че да са по-подходящи за атлетки в менопаузален преход.
В Германия книгата на журналистката Мириам Щайн Die gereizte Frau („Раздразнената жена“), издадена през 2022 г., стана много бързо бестселър на Der Spiegel и това провокира разгръщането ѝ в поредица – след нея се появиха Die weisen Frauen („Мъдрите жени“), а съвсем скоро от печат излиза и последната книга от трилогията – Die unverschämte Frau („Безсрамната жена“¹). Наскоро беше издаден и комиксът Peri Мeno на илюстраторката Рина Ланг.
Във Франция телевизионната журналистка Клер Фурние създаде подкаста Chaud dedans („Жега отвътре“), провокирана отново от болезнения личен опит, съчетаващ неинформираност и усещането, че няма към кого да се обърнеш (което е комбинирано и с представата за драматичен личен провал, когато се имаш за добър журналист, ерго – информиран човек, б.а.)
Сходни примери намираме в Нова Зеландия и Австралия, дори в Индия. Разказвам ви всички тези неща, за да ви улесня в намирането на информация. Но и за да е ясно, че по света ври и кипи и жените „на средна възраст“ са доста сигурни, че са тук, за да останат.
Ура, не сме на самотен остров!
В България често световният „хайп“ достига с известно закъснение. Нямам ясно обяснение защо е така, намираме се в сърцето на най-благоденстващия континент все пак (да влязат социолозите)! Но вълната, задвижена от жени като Анджелина Джоли и Холи Бери, през 2025-та – 2026-та явно най-после е заляла и нашия бряг.
Едно от най-разпознаваемите лица (или може би е по-подходящо да кажа „най-разпознаваемият глас“) на застъпничеството за повече информираност относно менопаузата е актрисата Силвия Лулчева. През 2025 г. тя става лице на информационната кампания „Изключи горещите вълни“ и споделя в поредица интервюта за личния си сблъсък с изострената тревожност, която я съпътства в този период. И не е единствена. За трудностите и позитивите на зрялата възраст говорят открито и колежките ѝ Маргита Гошева, Елена Петрова, Катерина Евро, журналистката Люба Пашова. Техните изяви обаче са част от рекламни кампании на различни брандове, а не лична кауза.
Ако трябва да сме честни, изкуственият интелект откри, че още във вече далечната 1996 г. у нас е била създадена Българската асоциация по менопауза и андропауза (БАМА). Организацията обаче има активна дейност едва няколко години, а през 2020 г. е официално заличена. От 2006 г. насам са регистрирани още три организации с аналогично име и предмет на дейност.
През последните две години се появиха няколко български инициативи с амбиция да подкрепят жените в прехода им към менопауза. Част от тях са специализирани програми на клиники за репродуктивна медицина, което е в някаква степен логично.
Стартъпът Womeno се опитва да събере всички нужди в една точка и да осигури както базови насоки и ориентация за жените къде по трасето на този преход се намират, така и най-сложното – да представи на потребителките си конкретни лекари от широк спектър специалности, които имат интерес и познания за особеностите и нуждите на жените в тази възраст.
Създадена е и фондация на име „Академия Менопауза – България“, която публикува периодично интервюта с български специалисти. От тази година съществува и платформата „Меноморфоза“. Зад нея стои Яна Балникова, чиято история повтаря познатото дотук – на 44 години се сблъсква с безсъние, изтощение, затруднена концентрация, а обяснението на лекарите, че наближава менопаузата, върви с препоръката да свиква. Търсенето на по-удовлетворително решение се превръща във видеоканал в социалните мрежи, уебсайт с информация, ръководства и дневник за проследяване на симптомите. В световния ден на менопаузата беше представена и едноименната книга с експертни отговори и лични истории. Самата Яна пък е пример как подкрепата за жените в сходно положение може да бъде стимул и за развитие на личен бизнес.
Наред с това през последните две години в София се проведоха най-малко пет събития, посветени на „жената в преход“, и изглежда, всички те са се радвали на интерес. Този списък, разбира се, не претендира за изчерпателност. Но с него обръщам внимание, че част от инициативите не са особено активни и от публичните им канали дори не става ясно дали все още функционират. А тези, които са, без изключение са част от маркетингова стратегия, при която образоването на жените е част от маркетинговата политика на даден продукт или услуга.
Това е проблем, защото затруднява жените при ориентирането коя от рекламните препоръки е наистина основана на наука и има ли как да си помогнат, ако не могат да отделят сериозна сума. Ето как менопаузалното здраве се превръща от право в индустрия.
Един пример до какво води това, е разминаването между стремежа
да останем здрави, докато сме живи, и превръщането на вечната младост в култ и символ на успеха.
На фона на десетилетните усилия на феминизма да зачеркне или поне да обуздае култа към слабото женско тяло, към силиконовите форми и хирургически опънатата кожа, която уж крие възрастта, сравнително новото движение за менопаузално здраве наля живително гориво у тези вредни за жените тенденции.
От Холивуд до София обещанието за вечна младост вече си има и име, което звучи почти като медицинска специалност – longevity (лонджевити, в случай че не знаете). Гуинет Полтроу разказва пред ELLE за венозните вливания с модерното вещество NAD+, а марката ѝ Goop слага същата съставка в крем. В София медицински центрове предлагат такива вливания като „антиейджинг“ терапия или като „ъпгрейд“ на клетъчно ниво – практика, която при недостатъчен контрол може да се окаже дори опасна за живота.
Засега няма убедителни данни, че тези процедури забавят стареенето, но пък има данни за нежелани странични реакции – американската Агенция по храните и лекарствата обяви, че е получила сигнали за тежко втрисане и повръщане след употреба на инжекционни препарати с NAD+.
И докато обсъждаме как да си върнем младостта на клетъчно ниво, рискуваме да приемем за даденост, че видимата възраст на една жена е проблем, който тя е длъжна да реши за своя сметка, за да докаже социалната си ценност. Или да го кажем по-просто –
окей, вече ни е социално разрешено да остаряваме, но само ако не ни личи.
При това положение може ли да се сърдим, че за жените краят на младостта изглежда като край на живота?
Въпросът е риторичен.
Иска ми се покрай целия този шум около менопаузата да извоюваме нещо съвсем практично – да можем да остаряваме на видно място и когато имаме нужда от компетентни грижи, да знаем къде да ги търсим и да можем да ги получим.
1 Книгите не са издавани на български език. Всички преводи са на авторката на текста. – Б.р.
С финансовата подкрепа на Български фонд за жените и Европейския съюз. Изразените възгледи и мнения са единствено на автора(ите) и не отразяват непременно тези на Български фонд за жените, Европейския съюз или Европейската изпълнителна агенция за образование и култура. Нито БФЖ, нито ЕС, нито ЕИАОК могат да бъдат държани отговорни за тях.
Metasploit Wrap Up: Breaking Zimbra’s Identity Boundaries
Post Syndicated from Christopher Granleese original https://www.rapid7.com/blog/post/pt-metasploit-wrap-up-breaking-zimbra-s-identity-boundaries
This release we have three pull requests from jburgess-r7 building out coverage for the identity-boundary issues detailed in Rapid7’s Breaking Zimbra Identity Boundaries, Part One research.
First up is a new shared mixin, Msf::Exploit::Remote::HTTP::Zimbra, which gives every current and future Zimbra module a common foundation for account/admin SOAP authentication, canonical identity resolution, mailbox-server lookup, and version parsing, allowing future modules to stay focused on the vulnerability instead of re-implementing Zimbra’s SOAP plumbing.
Built on top of that mixin are two new modules targeting CVEs from the same research track:
CVE-2026-73571 (#22080) It’s an authorization bypass in Zimbra’s SaveDraftRequest handling that lets an ordinary authenticated user send mail as another local mailbox without a delegation grant, landing a message in the victim’s own Sent folder in the process.
CVE-2026-93637 (#22070) Is a rate-limit bypass in Zimbra’s Network Edition GraphQL authentication endpoint, which lets credential-stuffing attempts skip the source-IP lockout counter that normally protects the SOAP login path.
Both modules were validated against live Zimbra 10.1.16 Network Edition instances. Super cool contributions from our very own jburgess-r7.
New module content (6)
Zimbra SaveDraftRequest Email Impersonation
Authors: Ayoub Nabil Boubagrat and Crypto-Cat
Type: Auxiliary
Pull request: #22080 contributed by jburgess-r7
Path: admin/http/zimbra_email_impersonation
CVE reference: CVE-2026-73571
Description: Adds an auxiliary module for CVE-2026-73571, allowing an authenticated user to send email as another local mailbox on Zimbra 10.1.16. The module supports optional Inbox delivery verification.
Zimbra GraphQL Authentication Rate Limit Bypass
Author: Crypto-Cat
Type: Auxiliary
Pull request: #22070 contributed by jburgess-r7
Path: scanner/http/zimbra_graphql_brute
CVE reference: CVE-2026-93637
Description: This adds an auxiliary scanner for CVE-2026-93637 that tests Zimbra Network Edition authentication through GraphQL batches. The module supports configurable batches, safe stopping controls, and storage of verified credentials.
BeyondTrust Remote Support MRS Origin Validation File Upload
Author: jheysel
Type: Exploit
Pull request: #22083 contributed by jheysel-r7
Path: linux/http/beyondtrust_rs_mrs_file_upload
CVE reference: CVE-2026-102764
Description: Adds an exploit module for an origin validation vulnerability in Beyond Trust Remote Support which allows for unauthenticated file upload resulting in RCE. The vulnerability is tracked as CVE-2026-102764.
Openfire Deleted Administrator Account Authentication Bypass RCE
Authors: Admin9961, Jatin Mannepalli, h00die-gr3y [email protected], and xRogue
Type: Exploit
Pull request: #22043 contributed by mjatin2007
Path: multi/http/openfire_deleted_admin_rce_cve_2024_25420
CVE reference: CVE-2024-25420
Description: Adds exploit module for CVE-2024-25420, an vulnerability in Ignite Realtime Openfire before 4.8.1 that allows a remote attacker to escalate privileges via the admin.authorizedJIDs system property component.
Cisco Secure Email Gateway AMP Arbitrary File Write RCE
Author: sfewer-r7
Type: Exploit
Pull request: #22028 contributed by sfewer-r7
Path: unix/smtp/cisco_secure_email_gateway_amp_file_write_rce
CVE reference: CVE-2026-76519
Description: Adds a new exploit module for CVE-2026-76519 an unauth RCE in Cisco Secure Email Gateway which was disclosed last month by the vendor and reported as being exploited in-the-wild. The vulnerability is a file write in the Advanced Malware Protection (AMP) File Reputation feature. When processing a TAR file which contains a PAX archive, we can force an existing file to be overwritten. The module overwrites an existing script /data/bin/core_watch.sh with a Metasploit payload. This script file is executed every 5 minutes by a cron job, giving us RCE with root privs.
Cisco Secure Email Gateway ECS Message-ID SQL Injection RCE
Author: sfewer-r7
Type: Exploit
Pull request: #22024 contributed by sfewer-r7
Path: unix/smtp/cisco_secure_email_gateway_ecs_sqli_rce
CVE reference: CVE-2026-76461
Description: This adds an exploit module for an unauthenticated SQL injection in the Cisco Secure Email Gateway (SEG) Email Cloud Scanner (ECS) URL-retrospective message database. We believe this is CVE-2026-76461 being tracked as, which was reported as being exploited in-the-wild last month as a zero-day.
Enhancements and features (2)
- #22055 from kx7m2qd – Improve ADSelfService Plus check result clarity.
- #22091 from jburgess-r7 – This adds a shared Zimbra SOAP support for account and administrator authentication, account discovery, and version retrieval. Zimbra modules can now reuse consistent token routing, response validation, and error handling.
Bugs fixed (24)
- #21879 from JothamB – Fixes a crash in the exploits/windows/local/unquoted_service_path module.
- #21931 from Pushpenderrathore – Improves the performance of Malleable profiles in versions of Ruby older than or equal to version 3.1.
- #21948 from s-r-e-e-r-a-j – Fixes a crash when running Metasploit with Apktool 3.x.
- #21968 from pauljccode – Fixes a crash when running Android payload generation.
- #21986 from Aaditya1273 – Fixed OptArray normalization so accepted values that differ only by capitalization are canonicalized and deduplicated correctly.
- #21991 from pauljccode – Fixes intermittent UDP receive failures when routing traffic through a Quectel modem session.
- #22026 from kx7m2qd – Fixes a warning message when running the SNMP login scanner module.
- #22062 from Yeagerist0 – Fix dlink_dir_645_password_extractor crashing after it extracts credentials.
- #22063 from Yeagerist0 – Fixes NoMethodError in auxiliary/scanner/misc/oki_scanner.
- #22074 from bc-idpotat – Skip invalid SPNs during LDAP enumeration.
- #22075 from Yeagerist0 – Removes duplicate target prefix from vnc_login module output.
- #22076 from Yeagerist0 – Removes duplicate target prefix from rsh_login and rlogin_login module output.
- #22078 from Yeagerist0 – Fixes auxiliary/scanner/http/coldfusion_locale_traversal ignoring FINGERPRINT when FILE is set.
- #22079 from Yeagerist0 – Fixes a crash when running the xorcom_completepbx_diagnostics_file_read module.
- #22087 from Yeagerist0 – Reject invalid bytes in the binary encoding checker.
- #22105 from dwelch-r7 – Updates the msfdb bootstrap capabilities when creating and securing a created PostgreSQL database.
- #22107 from jankesec – Removes duplicate peer:port prefixes from several scanners.
- #22108 from jankesec – Removes duplicate peer:port prefixes from several scanners.
- #22111 from cgranleese-r7 – Adds additional validation to Metasploit’s hardware bridge support.
- #22116 from Army-R – Updates the post/windows/manage/enable_rdp module’s error handling.
- #22128 from sjanusz-r7 – Fixes false positives reported by the check method for auxiliary/gather/solarwinds_webhelpdesk_backdoor.
- #22142 from Yeagerist0 – Fixes Msf::RPC::JSON::Request rejecting valid JSON-RPC responses as InvalidResponse when symbolize_names: false is used.
- #22143 from urvalkheni – Fixes a crash when running the pihole_domains_api_exec module when a token is not found.
- #22151 from sjanusz-r7 – Fixes a false positive result in the auxiliary/scanner/http/litellm_proxy_sqli vulnerability detection check.
Documentation added (1)
- #21937 from satanonsteroids2024-zzz – Updates the msfvenom help menu documentation.
You can always find more documentation on our docsite at docs.metasploit.com.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest. To install fresh without using git, you can use the open-source-only Nightly Installers or the commercial edition Metasploit Pro
nginx2root: Five new nginx vulnerabilities, and how Cloudflare protects origins from the worst of them
Post Syndicated from Dan Jones original https://blog.cloudflare.com/nginx2root/
On November 18, 2026, F5 and nginx.org disclosed ten vulnerabilities in nginx. Five of them, detailed by the Xint research team and published under the name nginx2root, are memory corruption flaws that an unauthenticated attacker can use to crash an nginx worker or, per Xint's research, run commands on the server. Xint also found a Linux kernel bug that turns that foothold into root on the host, including from inside a Docker container. Other teams found the two HTTP/2 bugs independently: F5 also credits Rapid7, Wiz Research and Ikotas Labs for CVE-2026-123007, and Metnir, Wiz Research, and Palo Alto Networks Unit 42 for CVE-2026-123633.
nginx is an HTTP web server that also serves as reverse proxy, content cache, load balancer, TCP/UDP proxy server, and mail proxy server. nginx runs a large share of the world's web servers, so this is a patch-now event. But if your nginx server is reachable only through Cloudflare's proxy, attackers cannot reach the vulnerable code paths for the most serious of these bugs, giving you protection while you update your servers.
Here is where Cloudflare stands, what that protection covers, where it stops, and how the bugs work.
The short version
- Cloudflare's edge is not affected. Much of the proxy that handles customer traffic at our edge now runs on FL2, written in Rust. We reviewed the parts still built on our heavily modified nginx fork against all five bugs before disclosure, and an update closing the related code paths finished rolling out globally before the vulnerabilities were published. The same releases fix five other nginx CVEs, including CVE-2026-118899, an infinite loop while reading a request body over TLS 1.3.
- Origins behind Cloudflare's HTTP proxy are shielded from the HTTP/2 and HTTP/3 attacks. For proxied hostnames, Cloudflare terminates every client HTTP/2 and HTTP/3 connection at our edge and opens a separate connection to your origin. The attacker's frames never reach your nginx.
- The resolver and mail proxy vulnerabilities depend on specific configuration. Many configurations of nginx will not be vulnerable, but the safest way to be sure is to update your install or disable features.
- You should still patch. Update to nginx 1.30.7 or 1.31.9 (or your vendor's fixed build) and restart. Some configurations, covered below, are not protected by the proxy.
What was disclosed
nginx2root is five independent bugs. Each one works on its own and each one needs a different configuration.
|
CVE |
Bug class |
Affected configuration |
First affected release |
|
CVE-2026-123007 |
Integer overflow leading to out-of-bounds heap read/write |
HTTP/2 enabled |
1.9.5 (2015) |
|
CVE-2026-123633 |
Use-after-free |
HTTP/2 with |
1.19.7 |
|
CVE-2026-121810 |
Use-after-free |
HTTP/3 (QUIC) with |
1.25.0 |
|
CVE-2026-123634 |
Use-after-free |
|
0.6.18 |
|
CVE-2026-113425 |
Use-after-free |
Mail proxy with |
0.5.33 |
F5 rates each one High (CVSS 3.1: 8.1) and Critical (CVSS 4.0: 9.2), and notes that code execution requires disabling or bypassing ASLR (Address Space Layout Randomization). For CVE-2026-123007, Xint's write-up shows how it leaked memory addresses to do exactly that.
CVE-2026-123007 is the one to worry about most. It only needs HTTP/2 turned on, which is commonly enabled on TLS deployments, and it has been in every nginx release since HTTP/2 support shipped in 1.9.5. Xint ran the exploit over the public Internet against servers on AWS, GCP and Azure. Xint searched Shodan on November 10, before the disclosure, and found 56.7 million hosts matching product:nginx. Of the 11.94 million that reported a version, 98.9% fell in the affected range. As of November 19, Censys's nginx2root exposure tracker counts about 8.8 million services running a potentially affected version with HTTP/2 enabled. Version strings don't prove a host is vulnerable, since distributions backport fixes, but the exposure is large.
The same nginx releases also fix five other bugs. The most serious, CVE-2026-118899, is an infinite loop when reading a request body over TLS 1.3 that lets an unauthenticated attacker stall a worker, in nginx 1.13.0 and later.
The Linux kernel bug is the sixth part of nginx2root. Xint found a use-after-free in the kernel's SCTP send path, present since Linux 4.15 (2018): while a send operation waits, its SCTP association can be moved to another socket, and the waiting send can then free it. An attacker who already runs code as the nginx worker can use it to gain root on the host, and Xint did this from an nginx running inside a Docker container. Many distributions load the SCTP module automatically the first time a program opens an SCTP socket, so hosts that never use SCTP can still be exposed. As of November 18, no kernel fix was available and Xint was withholding the details until there is one.
As of November 19, none of the five nginx2root CVEs is in CISA's Known Exploited Vulnerabilities catalog, and we have not seen reports of exploitation in the wild. Xint and Wiz Research have not released their exploits. Rapid7 has published a proof of concept, which it describes as suitable only for demonstrating the attack against a freshly started local container. Fake 'exploits' are also circulating on GitHub.
Why Cloudflare's proxy protects your origin
nginx2root's most dangerous bugs live in how nginx parses and manages HTTP/2 and HTTP/3 connections. To trigger them, an attacker has to send a carefully ordered stream of protocol frames directly to the nginx process: billions of WINDOW_UPDATE frames, a SETTINGS frame that holds response data back, PING frames that fill the send buffers, partial HEADERS frames, RST_STREAM at exactly the right moment.
When your DNS record is proxied through Cloudflare, that connection ends at our edge.
Cloudflare reads the client's HTTP request, applies your security and caching rules, and then makes its own request to your origin over a connection Cloudflare controls. The flow-control frames, pings, settings, and stream resets that the attacker sends are consumed by our edge. They are not forwarded. Your nginx only ever sees the requests Cloudflare chooses to send, framed the way Cloudflare frames them. This also holds when Cloudflare connects to your origin over HTTP/2: Cloudflare runs its own flow control on that connection and sends WINDOW_UPDATE and RST_STREAM frames only as its own traffic needs, so a client can't make it relay the billions of WINDOW_UPDATE frames the attack requires.
Rapid7 makes the same point in its analysis of CVE-2026-123007: if the HTTP/2 connection is proxied, the attacker's frames "will likely not be retransmitted" in a way that allows exploitation. This breaks each of the HTTP/2 and HTTP/3 attacks.
|
CVE |
What the attacker needs |
Behind Cloudflare's HTTP proxy |
|
CVE-2026-123007 |
Direct control over HTTP/2 |
Protected. Control frames terminate at Cloudflare's edge. |
|
CVE-2026-123633 |
The first part of a HEADERS frame on a direct HTTP/2 connection, plus the ability to exhaust nginx connection slots and reset the TCP connection |
Protected. The client's HTTP/2 connection terminates at Cloudflare. |
|
CVE-2026-121810 |
A direct QUIC/HTTP/3 connection to nginx |
Protected. HTTP/3 terminates at Cloudflare's edge. We do not communicate to origins over HTTP/3 |
|
CVE-2026-123634 |
A request and its mirror or SSI subrequest waiting on the same DNS lookup, and the main request ending while the answer is processed. In Xint's exploit, nginx's resolver had to reach the attacker's DNS server. |
Not fully protected. Depends on how your config builds |
|
CVE-2026-113425 |
A direct IMAP/POP3/SMTP connection to the nginx mail proxy |
Not protected. Cloudflare's HTTP proxy does not carry mail traffic. |
There is one condition to be protected by Cloudflare here: your origin must not be reachable directly. If an attacker can find your origin's IP and connect to it directly (TCP 443 or 80 for HTTP/2, UDP 443 for HTTP/3, or the mail ports), Cloudflare isn't in the path and the protection doesn't apply. You should ensure that your origin servers can only be accessed through Cloudflare’s proxies, using one of the following approaches:
- Cloudflare Tunnel. Your origin makes an outbound-only connection to Cloudflare and exposes no inbound ports.
- Firewall to Cloudflare IP ranges. Accept inbound HTTP/HTTPS only from Cloudflare's published IP ranges. This must be done using an IP firewall, not based on configuration in your nginx server.
- Authenticated Origin Pulls (mTLS). Your origin rejects any TLS connection that doesn't present Cloudflare's client certificate.
Xint's own exposure check makes the same point: "If a CDN or reverse proxy sits in front of nginx, the test only reaches the proxy, so also run it directly against the nginx server."
Where the protection does not apply
There are several situations in which Cloudflare’s HTTP proxy does not provide protection.
- Spectrum TCP/UDP applications. For these configurations, traffic from the Internet is passed unmodified through to your origin. If your origin is running nginx, patch or disable the affected features.
- nginx mail proxy. Cloudflare's HTTP proxy does not carry IMAP, POP3 or SMTP. Restrict mail listeners to trusted networks until patched.
- CVE-2026-123634 (resolver). This depends on how your configuration builds the
proxy_passtarget from the request, combined with a carefully timed cancellation of an HTTP request. Passing your traffic through Cloudflare’s proxy makes it harder to exploit this, but does not provide full protection. Update regardless. - DNS-only (grey-cloud), internal or non-proxied nginx. Any nginx server an attacker can reach without going through Cloudflare, including internal services behind a compromised host, needs to be patched.
Cloudflare’s WAF rules are not relevant to these vulnerabilities. These are protocol-level bugs. Because Cloudflare’s proxy handles parsing the HTTP protocol messages, and creates new messages to fetch information from origin servers, origins behind Cloudflare's HTTP proxy are protected from the HTTP/2 and HTTP/3 bugs without needing a rule. We have therefore not released a managed rule. The protection comes from connection termination, not from pattern matching.
What to do now
- Find every nginx server. Include nginx Plus, distribution packages, container images and appliances. Run
nginx -Vandnginx -Ton each and note HTTP/2, HTTP/3/QUIC listeners,proxy_passwith variables plus SSI ormirror, and anymailblock. - Patch. Update nginx Open Source to 1.30.7 or 1.31.9, nginx Plus to 37.0.8.1 or 37.3.0.1, or your distribution's fixed package. F5 lists nginx Plus R34 to R36 as affected with no fixed build, so move those to a fixed 37.x release. Then restart nginx or complete a binary upgrade. A config reload does not replace the running binary.
- Check backport versions carefully. Distributions often patch without changing the version
nginx -vreports. Compare the full package version against your distribution's advisory. - Make sure your origin is only reachable through Cloudflare. Use Tunnel, IP allowlisting or Authenticated Origin Pulls.
- If you can't patch yet, disable what you don't need.
http2 off;(nginx 1.25.1 and later; on older versions, removehttp2from thelistendirective) blocks CVE-2026-123007 and CVE-2026-123633. Removing QUIC listeners and settinghttp3 off;blocks CVE-2026-121810. Pointproxy_passat fixed upstream groups for CVE-2026-123634. Don't rely onmirror_request_bodyalone: Xint's tested setup set it tooff, and the defaultonstopped that exploit, but SSI and other subrequests can still reach the bug. Bind mail listeners to trusted networks for CVE-2026-113425. Restart so old connections close. - Block SCTP if you don't use it. Add
install sctp /bin/falseto a file in/etc/modprobe.d/to stop the kernel module from loading. This doesn't unload an already-loaded module or disable SCTP built into the kernel. When your distribution ships a kernel update for the SCTP bug, install it and reboot. Blocking the module is a stopgap until then.
The Cloudflare Radar Zero Wire entry for nginx2root has the full checklist, a prompt you can give an agent to run a read-only assessment of your fleet, and links to every vendor advisory.
Technical deep dive
Let’s dig into the details of the five bugs by looking through the code. We’re looking at nginx 1.31.8 (commit 140aa94) which was the most recent code published before the fixes, and comparing this to the fixes in 1.31.9 (which were also included in release 1.30.7 on the stable branch).
A note on methodology: we based our analysis on the public advisories, and to verify our reading of the code, we built the public 1.31.8 and 1.31.9 releases with AddressSanitizer and ran tests for four of the five bugs (flow control, HTTP/2 use-after-free, resolver and mail proxy). Each one faults on 1.31.8 and runs clean on 1.31.9. We did not reproduce the HTTP/3 bug; that section is based on the fix commit and the published analysis.
One pattern, in four places
Four of the five bugs are use-after-free bugs. This is a common issue with programs that manually manage memory without language support: one part of the code frees an object that another part is still using.
nginx is event driven. A handler runs, calls other code, and that code returns to the handler. Three of the bugs occur when the called code tears down the connection or request the handler is working on. In the fourth, a second connection still holds a pointer to the object.
- CVE-2026-123633 and CVE-2026-121810. A request needs a connection slot to reach its upstream. nginx is low on slots, so it closes an idle connection to free one. The connection it chooses is the one the request belongs to.
- CVE-2026-123634. A resolver callback ends a request. Cleanup of that request frees a second resolver context that the resolver is about to call next.
- CVE-2026-113425. When a write to a mail client fails, the client connection is closed while the connection to the authentication service still points at its session.
F5 rates all four as potential code execution if address space layout randomization (ASLR) is disabled or bypassed, and in its tests Xint reports code execution with the privileges of the nginx worker.
The fifth bug, CVE-2026-123007, is of a different kind: an accounting error that becomes a length error.
CVE-2026-123007: two flow-control pieces that each look correct
HTTP/2 flow control limits the amount of response data a server may send. nginx tracks a send window for each stream and one for the connection, h2c->send_window. The client enlarges a window with a WINDOW_UPDATE frame, and the protocol caps every window at 2^31 − 1.
nginx enforces that cap when a WINDOW_UPDATE arrives (ngx_http_v2_state_window_update()):
if (window > NGX_HTTP_V2_MAX_WINDOW - h2c->send_window) {
   /* logs "client violated connection flow control" */
   return ngx_http_v2_connection_error(h2c, NGX_HTTP_V2_FLOW_CTRL_ERROR);
}
On its own, this check is correct. But the connection window also grows in a second place. When nginx queues DATA frames for a stream, it subtracts their length from the window. If the stream is canceled before those frames go out, ngx_http_v2_filter_cleanup() takes them off the queue and returns the credit:
h2c->send_window += window;Nothing caps this line. As the fix commit describes, if the client enlarges the connection window after the frames are queued and before the stream is terminated, the refund pushes the window past 2^31 − 1.
From that point the first check no longer works. h2c->send_window is an unsigned size_t, so NGX_HTTP_V2_MAX_WINDOW - h2c->send_window wraps around to a very large number and every subsequent WINDOW_UPDATE is accepted. The client can then raise the window as far as it wants.
The window is unsigned, but the code that sizes DATA frames compares it as a signed value (ngx_http_v2_send_chain()):
if (limit == 0 || limit > (off_t) h2c->send_window) {
   limit = h2c->send_window;
}
...
if ((off_t) frame_size > limit) {
   frame_size = (size_t) limit;
}
After the window passes 2^63, it is negative as an off_t. The frame size becomes the window value itself, a number between 2^63 and 2^64, and nginx builds a buffer whose last pointer lies before its pos pointer.
Over TLS, that buffer reaches a memcpy() in ngx_ssl_send_chain() with that length. Our TLS test stops at that point under AddressSanitizer. Xint's write-up explains how, with the window pushed close to 2^64, this turns into a controlled out-of-bounds write and an address leak, and Xint, Rapid7, and Wiz each report code execution from it. This post goes no further than the fault.
Over cleartext HTTP/2, the same invalid buffer follows a different output path. Our cleartext test also faults under AddressSanitizer on 1.31.8 and runs clean on 1.31.9. The public write-ups address the TLS case.
How much traffic the known attacks require
The biggest step a WINDOW_UPDATE can take is 2^31 − 1, and a WINDOW_UPDATE frame is 13 bytes. Bringing a 64-bit window near its top therefore requires about 2^33 frames: roughly 8.6 billion frames, or about 112 GB (104 GiB).
Rapid7, which published a proof of concept, gives the same figure and adds that nginx limits control-frame traffic relative to other traffic on the connection, so its run also sends about 15 GiB of other request traffic. Its total comes to approximately 128 GB of HTTP/2 data: about two minutes on a 10 Gbit/s link and about seventeen minutes at 1 Gbit/s. Rapid7 estimates the WINDOW_UPDATE traffic needed to reach 2^63 at about 2^32 frames, or 52 GiB, half of the 104 GiB figure. It also notes that these figures describe its route and are not a proven minimum.
For defenders, this is the useful fact about the bug. At this volume, the known attacks are hard to hide: nginx receives tens of gigabytes from a single client over one long-lived connection and sends little back, much more than the requests in the access log account for.
Why it was difficult to find
The refund line has existed in nginx since HTTP/2 support arrived in 1.9.5 in 2015. Two things made it difficult to notice.
First, each piece looks correct on its own. The check on WINDOW_UPDATE is the right check. The refund is the right refund. The bug is that the check relies on an assumption the refund does not preserve.
Second, testing that waits for a crash is very unlikely to reach it, because a crash requires tens of gigabytes of input. The bad state itself can be reached with very little traffic: Censys published a cleartext test that reaches what it calls the corrupted flow-control state with a 5.69 MB capture. A test that asserts "the send window never exceeds its protocol maximum" after every frame would flag the bad state as soon as a test sequence got there. A test that waits for memory corruption would not.
The fix
The fix (6 lines added) introduces a counter, h2c->send_queued, for DATA that is queued but not yet sent. The WINDOW_UPDATE check now includes those bytes in the window:
if (window > NGX_HTTP_V2_MAX_WINDOW - h2c->send_window - h2c->send_queued) {From the client's perspective, queued frames still count toward the window, so the client can no longer refill credit that nginx is about to refund. On a fixed version the attempt is rejected with a flow-control error.
CVE-2026-123633: where two protections interact
An nginx worker has a fixed number of connection slots (worker_connections), which the client and upstream connections share. Since 1.19.2, when free slots run low (1/16 of the total or fewer), ngx_get_connection() calls ngx_drain_connections(), which closes connections marked "reusable": connections with nothing in progress, such as idle keep-alive connections.
This works only if a reusable connection truly has nothing in progress. For HTTP/2 that was not always the case. Two commits landed on the same day in February 2021 and were released together in 1.19.7:
- "HTTP/2: fixed reusing connections with active requests" fixed a case in which a cleartext HTTP/2 connection could remain reusable while it had a request.
- "HTTP/2: reuse of connections with incomplete frames" registered a connection as reusable while it waits for the remainder of a partly received frame, so that a client cannot hold slots with partial frames.
The second change is the relevant one here. As the fix commit explains, if the remainder of that frame is a HEADERS frame, a stream is created, but the reusable status was not reset until the connection next went idle. The connection then has a request and remains in the reusable queue.
If that request is proxied, nginx requests a slot for the upstream connection. If slots are short, the drain runs inside that call and can choose this same connection. The drain instructs the connection to close and nginx attempts to send GOAWAY. If that send fails, nginx frees the connection and every stream on it. Control then goes back to the upstream code, which continues to use the request it was called for.
Each change made sense on its own. The interaction between them was subtle and stayed unnoticed until this year. F5's advisory credits Albert Ebb of Metnir, Nir Ohfeld at Wiz Research, Xint.io and memN0ps of Palo Alto Networks Unit 42; nginx.org's changelog credits Albert of Vexera AI.
The fix
Two lines added: ngx_http_v2_create_stream() now calls ngx_reusable_connection(h2c->connection, 0). A connection that has a stream is never reusable, regardless of the state it was in before.
CVE-2026-121810: the same idea, in QUIC
According to the fix commit and Xint's analysis, the HTTP/3 bug reaches the same result by a different route.
In nginx's QUIC code, each QUIC connection uses one connection slot and each stream uses another. A QUIC connection may be drained only when every stream remaining in its tree can be cancelled, and nginx determines this by walking the connection's tree of streams.
ngx_quic_create_stream() removes the QUIC connection from the reusable queue and then requests a slot for the new stream. Before the fix, the new stream was added to the tree only after that. If the slot request triggered a drain that closed another, idle stream of the same QUIC connection, the code handling the closed stream walked the tree, did not find the stream being created, concluded the connection was idle, and made it reusable again. A later drain, for example when the new request connects to its upstream, could then close the QUIC connection while that request was running.
F5's advisory states that exploitation "also depends on conditions beyond the attacker's control". Xint writes that the bug "is triggered by a slightly different mechanism" from the HTTP/2 one.
The fix
Four lines added: the stream goes into the tree before the slot is requested, and is taken out again on the error paths.
CVE-2026-123634: freeing the next item of a list during the walk
When proxy_pass contains a variable, nginx resolves the host name while handling the request. If a lookup for the same name is already in progress, the new request waits on the same resolver node. When the answer arrives, nginx detaches the list of waiting contexts and calls each in turn:
next = rn->waiting;
rn->waiting = NULL;

while (next) {
   ctx = next;
   ...
   next = ctx->next;

   ctx->handler(ctx);
}
The loop stores next before the handler call, so a handler may free its own context. The trouble starts when a handler frees a different context in the same list. This happens when two contexts belong to one request, as with a request and its mirror subrequest resolving the same name (the case Xint tested; F5 also lists SSI subrequests). If the first handler ends the request, the request's cleanup calls ngx_resolve_name_done() for the second context. That function searches the node's waiting list for the context, does not find it because the list has been detached, and frees the context regardless. The loop then advances to the freed context.
Usually nginx logs this. On vulnerable versions, when the search fails, it writes
could not cancel <name> resolvingto the error log at alert level. This line is worth searching for. It is not proof either way: the fix commit notes that one variant, while following a CNAME, produced no alert.
The fix
A context cancelled while it sits in a detached list is no longer freed immediately. Its handler is swapped for one that frees it when the loop gets to it (31 lines added). The fix also downgrades the alert to a debug message, so the line above shows up at alert level only on unpatched versions.
CVE-2026-113425: two connections, one session
With auth_http, the mail proxy asks an HTTP service to verify each login. During the wait, it holds two connections for one session: the client connection and the connection to the authentication service. The second points at the session and uses the memory pool of the client connection.
Before the fix, the reply the protocol handler had prepared for the client remained queued while the authentication request was in progress, and the client's write handler was still ngx_mail_send(). If that handler ran and the write failed because the client had reset the connection, it closed the client connection and destroyed the session. The authentication connection still pointed at the session, and the next event on that connection used freed memory.
Xint describes two conditions for this: the client's write event must already be registered (for example, because the client stopped reading replies), and the login command and the reset must be handled in the same pass of the event loop. Valid credentials are not needed, because this happens before the login is checked.
The fix
Two added lines discard the queued reply when the authentication request begins. The same release contains three further commits that block client writes while the proxy waits for the authentication response, while it connects to the upstream and reads its greeting, and while it resolves an SMTP client's address and name.
What the fixes share
The five fixes each involve minor corrections to the code. They add between 2 and 31 lines each, and the mail proxy fix came with three further commits. There is no design change needed. Each fix restores an invariant that the rest of the code already depended on:
- a send window never goes above the protocol maximum
- a connection with a request in progress is never reusable
- an object that other code is about to use is not freed out from under it
In every case, one code path failed to keep a rule that the rest of the code relied on, and the fix makes that path keep it. As code is modified over time, it is very easy for these kinds of rules to become broken.
What to watch for
Attempts to exploit this will typically trigger some characteristic log messages. Three of these messages (the two at info and the one at warn) fall below nginx's default error_log level of error and appear only if a lower level is set. The alert messages are logged by default.
|
Bug |
Log messages or other signals |
|
CVE-2026-123007 |
A single long-lived HTTP/2 connection on which nginx receives tens of gigabytes from a client and sends little back, much more than its logged requests account for. On fixed versions a rejected attempt logs |
|
CVE-2026-123633, CVE-2026-121810 |
|
|
CVE-2026-123634 |
|
|
CVE-2026-113425 |
Worker crashes in a mail proxy using |
|
All five |
Unexpected programs launched by an nginx worker process, for example from an |
Timeline
|
Date (UTC) |
Event |
|
Oct 11, 2026 |
Xint discovers the vulnerabilities |
|
Oct 16, 2026 |
Reported to F5 via HackerOne |
|
Oct 27, 2026 |
Reports delivered to the nginx development team |
|
Nov 10, 2026 |
Xint completes patch validation |
|
Nov 18, 2026 |
Public disclosure; nginx 1.30.7 and 1.31.9 released |
Closing
CVE-2026-123007 sat in nginx for more than ten years. The SCTP bug has been in the Linux kernel since 2018. Xint says one of its researchers found CVE-2026-123007 by hand and an automated Xint scan found the other four nginx bugs. Several other teams found the two HTTP/2 bugs independently. Meanwhile, nginx's advisory list has gone from two entries in 2025 to 36 so far this year. AI-assisted research is finding bugs in heavily reviewed code faster than before, and more disclosures like this one are coming.
That's a large part of why it's worth putting Cloudflare in front of your origin. A protocol bug in your web server becomes much less of a risk when the attacker can't speak that protocol to your server directly. Our edge is not affected, and the HTTP/2 and HTTP/3 attacks against your nginx end at our network. Patch anyway, lock down your origin so Cloudflare is the only way in, and use the Radar Zero Wire page to check your fleet.
Sources
- Cloudflare Radar Zero Wire: nginx2root
- nginx2root.com
- Xint: NGINX2Root technical write-up
- F5 advisory index K000164058
- nginx security advisories
- Rapid7: CVE-2026-123007 analysis and proof of concept
- Censys: nginx2root simple test
- Wiz: nginx HTTP/2 RCE vulnerabilities
- Censys: nginx2root exposure tracker
AI coding agents on Amazon EC2 Mac: How Cognition scales Devin for macOS
Post Syndicated from Adam Hesch original https://aws.amazon.com/blogs/architecture/ai-coding-agents-on-amazon-ec2-mac-how-cognition-scales-devin-for-macos/
When the Cognition team set out to give Devin, their AI software engineer, the ability to build Apple apps, they ran into a basic requirement: Devin needed a Mac. The process of building, testing, and signing apps for iPhone, iPad, and Mac requires both Apple hardware and macOS, regardless of who (or what) writes the code, which was not supported until a couple months ago. To give Devin access to a Mac development environment, Cognition now runs macOS environments on Amazon Elastic Compute Cloud (Amazon EC2) Mac instances. With access to cloud-based Macs, Devin can build an iOS app, run it in the iOS Simulator, and check how it behaves all before it hands back a merge-ready change.
Within six weeks of launch, nearly 1,000 organizations were running Devin on macOS, according to Cognition. Cognition starts a fresh macOS virtual machine (VM) for each Devin session in under a minute, using a fleet of EC2 Mac hosts across six AWS Regions. By Cognition’s estimate, that startup time puts customers into a working macOS environment 15–20 times faster than setting up a Mac host themselves.
This post explains why Devin needed its own Mac, how Cognition built Devin workspaces on EC2 Mac, and how to plan a macOS fleet for AI agents or automated testing.
Why an AI coding agent needs its own Mac
Prior to this launch, Devin Cloud ran sessions only on Linux and Windows VMs. Devin could write Swift code and syntax in those sessions, but without macOS and Xcode it couldn’t run or test the app, so it depended on a customer’s continuous integration (CI) system or the customer’s own Mac fleet to build and test. Even then, simply having a successful build doesn’t show whether the app behaves correctly. One example of testing behavior is where an iPhone game is designed to resume where the player paused it, even after the app closes; in order to check that behavior, a software development agent has to play the game, pause it, quit, relaunch, and confirm the saved state.
You can virtualize macOS, but a Devin workspace needs more than just a bootable virtual operating system environment. Cognition needed each macOS workspace to provide the same properties as its other cloud workspaces:
- A disk that keeps the work of a session, so an idle session doesn’t keep a VM running.
- Network access that follows the access rules of the session.
- A development environment that is ready before Devin starts.
- A way for both the user and Devin to see and operate the running app.
Why Cognition chose AWS
Cognition required macOS machines to scale Devin beyond Linux and Windows, but sought to avoid the overhead of buying, racking, and maintaining physical Mac computers. The following properties of EC2 Mac shaped the Cognition design:
- Apple silicon hardware in the cloud: Each EC2 Mac instance is a physical Mac mini or Mac Studio attached to the AWS Nitro System, so Cognition can run the Apple Virtualization framework on EC2 Mac the same way it would on an on-premises Mac.
- Capacity through an API: Cognition allocates Dedicated Hosts and launches Mac instances with the Amazon EC2 API, instead of ordering and shipping machines.
- Regions around the world: EC2 Mac is available in multiple AWS Regions, and Cognition runs in six of them.
- Standard AWS networking and storage: Mac instances run in an Amazon Virtual Private Cloud (Amazon VPC) and boot from Amazon Elastic Block Store (Amazon EBS) volumes, so Cognition manages them like other EC2 instances.
Solution overview
Cognition builds Devin macOS workspaces on EC2 Mac instances, which run as bare metal instances on Amazon EC2 Dedicated Hosts. Available with Apple silicon, these instances are built on Apple Mac computers and the AWS Nitro System.
Each EC2 Mac instance runs on its own Dedicated Host, which has a minimum allocation period of 24 hours, so Cognition separates the life of a Devin session from the life of a host. In Regions where they don’t have preallocated capacity, Cognition uses an Amazon EC2 Auto Scaling group to allocate and release Dedicated Hosts.
On each host in its fleet, a Cognition VM manager uses the Apple Virtualization framework to run macOS guest VMs from images that Cognition prepares and manages. Each bare metal EC2 Mac host runs two isolated Devin workspaces at a time, because the macOS Software License Agreement (SLA) (SLA) allows up to two additional copies of macOS in virtual operating system environments on each Mac, a limit macOS enforces. Idle Devin sessions release their VMs for other Devin sessions to use, so a singular host is able to serve multiple Devin sessions a day.
Figure 1 shows how one EC2 Mac Dedicated Host serves Devin sessions. The host runs a bare metal Mac instance in one of the six AWS Regions in the Cognition fleet, with one guest VM per active session. Each guest runs Xcode tools and the iOS Simulator with the app under test, plus a live view and an accessibility tree from accessibility-cli. The user’s browser exchanges video and input with the live view, and the Devin agent queries and acts on the accessibility tree.
On the host, the VM manager runs the guests with the Virtualization framework, while a snapshot process with a Network Block Device (NBD) frontend handles disk I/O for each guest and exchanges snapshots with snapshot storage. The Devin agent and snapshot storage also run on AWS as Devin Cloud services inside the same Region, with Devin sessions hosted on Amazon EC2 and snapshots stored in Amazon Simple Storage Service (Amazon S3) (Amazon S3). For networking, a user-space Ethernet gateway takes Ethernet frames from a guest and passes IP packets to macOS packet filter (pf) rules and proxies, which apply the session access rules and send allowed traffic to the internet.
Figure 1: Devin macOS sessions on an Amazon EC2 Mac Dedicated Host
Keep session state with disk snapshots
Much of the work users do with Devin Cloud is asynchronous, and an idle session doesn’t need a running VM, so Cognition leverages the same snapshot system for macOS as its Linux VMs. The snapshot system runs as a separate process on the host and handles the VM’s disk reads and writes. Because the guest operating system sees only an ordinary virtual disk, the guest doesn’t need to know about snapshots.
On Linux, Cognition connects VMs to this storage process with vhost-user. The Virtualization framework doesn’t support vhost-user, but it does support NBD attachments, so Cognition added an NBD frontend to its snapshot system and kept the same storage design behind the new frontend. When a guest shuts down, the storage process keeps running to persist pending writes and upload the updated snapshot. The VM manager waits for the upload to finish before it completes cleanup, so stopping a session doesn’t interrupt the work that saves it.
Cognition reports that about 90% of sessions give up their Mac VM when idle and resume from a snapshot in seconds. On average, a session frees and reclaims its VM multiple times, so Mac capacity goes to active work, not idle sessions.
Apply network access rules with a user-space Ethernet gateway
Devin Cloud applies the access rules of each session to outbound traffic and blocks access to protected host infrastructure. The Virtualization framework offers three ways to connect a guest to the network: bridged networking, network address translation (NAT), and a file-handle attachment, which exchanges raw Ethernet frames over a local Unix datagram socket. NAT needs the least setup, but the Apple implementation also manages rules in pf, the macOS packet filter. Because Cognition also uses pf for its network controls, the two systems raced to configure the same filter.
Cognition chose the file-handle attachment instead and built its own Ethernet gateway to run in user space on the host, giving each Mac VM a separate gateway and its own session policy enforcement. Each Mac VM has its own gateway and its own session policy enforcement. The gateway answers Address Resolution Protocol requests from the guest and validates Ethernet addressing. It also checks that the source IP address of each packet matches the address assigned to the guest. The gateway then passes accepted IP packets into a tunnel interface on the host, where pf rules and proxies route the traffic and apply the access policy of the session.
Prepare guest images before the first boot
A Devin workspace needs more than a fresh macOS install: a user account, a usable desktop, Xcode tools, and the permissions Devin needs to observe and control apps. A fresh install asks for permissions such as accessibility and screen recording in dialogs, and each dialog would block Devin until a person approved it.
To avoid those dialogs, Cognition mounts the guest image disk on the host and prepares its state directly, creating the user and updating the macOS internal configuration databases so the permissions are in place before the guest boots. Cognition then boots the prepared image to install the remaining developer tools, verify Xcode, warm up the iOS Simulator, and let Spotlight indexing and other background setup finish. Cognition also turns off background services development sessions don’t need. With all this preparation done ahead of time, a new session can start building and testing as soon as its VM starts.
Give users a responsive live view of the app
Users can watch the macOS desktop in a Virtual Network Computing (VNC) view and their app in a new iOS Simulator pane in the Devin session. From either view, users can also try the app themselves and take control when they want.
Figure 2 shows a recorded Devin session from Cognition, in which Devin builds a 3D iPhone game and tests it in the iOS Simulator while the session’s Computer pane shows the macOS desktop.”
Figure 2: Devin builds and tests a 3D iPhone game on macOS. Video courtesy of Cognition
Two steps decide whether the live view responds fast enough for users to operate the app: capturing the screen and delivering the video. For the macOS desktop, ScreenCaptureKit, the Apple desktop capture API, supplies screen images from a limited pool of reusable buffers. When Cognition needs to keep the last captured image, it keeps its own copy instead of holding a pooled buffer, because holding a buffer while the screen is idle can delay the next screen change.
After capture, the desktop and Simulator video is encoded, sent to the user’s browser, and displayed. When one stage can’t keep up, frames wait between stages, and the stream can look smooth while it shows an old state of the app. In the iPhone game example, a user might press Pause and still see the game move, because the viewer is still showing frames from before the press. To keep the view current, Cognition limits how many frames can wait between stages and doesn’t replay a stale backlog.
Because compressed video frames often build on earlier frames, dropping a frame can leave the frames after it impossible to decode. A keyframe doesn’t depend on earlier frames, so the decoder can start fresh from it. When the Simulator stream falls behind, it restarts from a recent keyframe or asks for a new one and skips the missed frames. Keyframes are part of the compressed video stream, so they’re separate from the screen images Cognition copies at capture.
Let Devin operate native apps through the accessibility tree
Like users, Devin needs to see and operate the app, and it also needs an efficient way to check the result of each action. Devin does this through computer use, which in its simplest form takes a screenshot, has a model find a control in the image, clicks it, and takes another screenshot. This loop is slow and costly across the many pause, quit, and relaunch paths that Devin tests compared to web apps, where browser automation is more efficient. This is because the browser exposes the page structure, so Devin can find a named button or read a field’s value without working from pixels.
Native macOS apps and apps in the iOS Simulator run outside the browser, but they expose a structure of their own: the accessibility tree. Built for assistive technologies, the tree describes each control by its role, name, value, state, and relationships to other controls. Cognition exposes this tree to the Devin computer-use tool, so Devin can confirm that a control is a Resume button instead of guessing from pixels. Devin queries for a control, acts on the reference the query returns, and then reads the tree again to report what changed. The following exchange, adapted from Bringing macOS to Devin, shows a query for a Resume button and the press that follows.
{ "action": "query", "target": "ios", "role": "button", "name": "Resume" }
The shortened result lists a reference, the control’s role, its accessible name, and the actions it supports.
@i17 button "Resume" {press}
Using that reference, Devin then presses the control.
{ "action": "act", "target": "ios", "reference": "@i17", "operation": "press" }
Cognition built these capabilities on the open source accessibility-cli project from Dioxus, which is now part of Cognition. The project provides accessibility, input, and screen capture building blocks, and Devin turns them into the observe, reference, and act loop shown here. Even with the accessibility tree, Devin still relies on screenshots to check how the app looks. In the game example, a closed pause menu doesn’t prove the game restored the player’s position, because the app might draw gameplay directly instead of describing it in the tree.
Results
Cognition launched macOS support for Devin on September 15, 2026, and nearly 1,000 organizations were running Devin on macOS within six weeks. Devin no longer needs a customer’s CI system or Mac computers to build and test Apple apps, because it now builds, runs, and verifies iPhone, iPad, and Mac apps in its own cloud workspace. From that workspace, Devin also uploads builds to TestFlight, the Apple beta testing service.
“With Amazon EC2 Mac, we gave Devin macOS environments in the cloud, unlocking iOS and macOS development. Now customers can hand Devin platform-specific tasks such as building and testing iOS applications, without anyone managing Mac hardware. Our mac-m4pro.metal and mac-m4.metal fleet spans six regions, and we can mint fresh macOS VMs for Devin in under a minute.”
— Evan Almloff, Member of Technical Staff, Cognition
Wispr, which makes the Wispr Flow voice dictation app, uses Devin for macOS to test its iOS app end to end.
“At Wispr, a big part of testing our iOS app is making sure recording and transcription work end to end. The biggest blocker for us was end to end testing with Audio and Keyboard extension. With Devin’s macOS support, the pace of development has accelerated and it has given us more confidence in shipping features and triaging bugs. The velocity unlock is huge and cut down code review time by 70% and improved our velocity by nearly 2x.”
— Sumit Oberoi, Lead iOS Engineer, Wispr
Plan your own macOS fleet on EC2 Mac
The following points from the Amazon EC2 User Guide affect how you design a macOS fleet:
- Each Dedicated Host runs one Mac instance, and you can release a host only after its 24-hour minimum allocation period.
- You can share Dedicated Hosts with other AWS accounts or within an organization in AWS Organizations using Cross-account Amazon EC2 Dedicated Host sharing.
- Mac instances are available as On-Demand Instances, and you can lower their cost with a Savings Plan.
- Mac instance types are available in specific Regions, so check Amazon EC2 instance types by Region before you plan capacity.
Conclusion
Cognition gave Devin its own cloud Mac by running a fresh macOS guest VM for each session on Amazon EC2 Mac bare metal hosts. Disk snapshots, a user-space Ethernet gateway, prepared guest images, and accessibility-based control turn each VM into a workspace where Devin can build, run, and verify Apple apps.
Get started with Amazon EC2 Mac instances, and read Bringing macOS to Devin for more detail on how Cognition built Devin for macOS.
Resources
- Amazon EC2 Mac instances in the Amazon EC2 User Guide.
- Announcing Amazon EC2 M4 and M4 Pro Mac instances on the AWS News Blog.
- Amazon EC2 Dedicated Hosts pricing.
- Bringing macOS to Devin from Cognition.
About the authors
Announcing custom execution roles for AWS CloudFormation StackSets
Post Syndicated from Tanvi Ravindra Malali original https://aws.amazon.com/blogs/devops/announcing-custom-execution-roles-for-aws-cloudformation-stacksets/
With AWS CloudFormation StackSets, you can create, update, and delete stacks across many accounts and Regions from a single operation. By default, StackSets creates an execution role with AdministratorAccess in each target account, which requires no additional setup. With custom execution role templates, you can define the IAM role that StackSets uses in each member account instead.
This provides two capabilities. First, you can scope the execution role’s permissions to only what your workload needs. Second, service-managed stack sets can deploy templates that use nested stacks, macros, and transforms.
Note: Switching to a custom execution role does not remove the default AdministratorAccess execution role from member accounts. For true least-privilege access, delete the default role in each member account after you confirm the custom role works.
How it works
When you create or update a stack set with an execution role template, StackSets validates it and stores it. For each target member account, StackSets then deploys the template as a small bootstrapping stack that creates the IAM role. StackSets uses the name you passed in the ExecutionRoleName parameter for all subsequent operations. The StackSetExecutionRoleName output is used only to validate that the role the template provisioned matches that name.
The bootstrapping stack is created once per member account, always in the home Region of the partition (us-east-1 for commercial, cn-north-1 for China). It is named stacksets-exec-role-stack-<region>-<stackset-id>-<short-uuid>. From that point on, every create, update, and delete operation StackSets runs in that member account uses your custom role.
Templates with nested stacks, macros, and transforms
With a custom execution role, service-managed stack sets can deploy workload templates that use nested stacks (AWS::CloudFormation::Stack), CloudFormation transforms (such as AWS::Serverless-2016-10-31), and custom macros. Previously, these features were not supported in service-managed stack sets.
This capability applies to the workload template you deploy with your stack set, not to the execution role template itself. The execution role template must still follow the requirements in the next section, including no nested stacks and no transforms.
For a workload template that uses transforms or macros, such as a SAM template, pass both CAPABILITY_NAMED_IAM and CAPABILITY_AUTO_EXPAND when creating the stack set:
Prerequisites
Before you configure a custom execution role template, make sure:
- Your StackSet uses the service-managed permissions model. Custom execution role templates are not supported with self-managed permissions.
- Activate trusted access with AWS Organizations. This creates the
AWSServiceRoleForCloudFormationStackSetsOrgAdminservice-linked role in your management account. - You have your management account ID available for use in the trust policy.
Execution role template requirements
Your execution role template must meet all four of the following requirements. If any requirement is not met, CreateStackSet or UpdateStackSet returns a validation error.
1. A single IAM role resource
The template must contain exactly one resource, and that resource must be of type AWS::IAM::Role. Templates with multiple resources or non-IAM resources are rejected.
Note: Name the role with the required prefix stacksets-exec-custom- (for example, stacksets-exec-custom-my-role). The service’s default execution role is named stacksets-exec-<hash>, so this prefix is what lets StackSets tell a custom role from a default one by name alone. Roles without this prefix fail validation. Use the same role name across all stack instances. Don’t vary it per account or Region.
2. A trust policy for the StackSets service-linked role
The IAM role must include an AssumeRolePolicyDocument that grants assume-role access to the StackSets service-linked role in your management account. The trust policy must contain exactly one Statement and exactly one AWS principal, in this format:
arn:aws:iam::<management-account-id>:role/aws-service-role/stacksets.cloudformation.amazonaws.com/AWSServiceRoleForCloudFormationStackSetsOrgAdmin
Replace <management-account-id> with your organization’s management account ID.
If your organization uses a delegated administrator account for StackSets, the trust policy must still reference the organization management account rather than the delegated administrator account.
You can optionally strengthen the trust policy with a condition on your organization ID:
3. A required output
The template must define a CloudFormation output with the key StackSetExecutionRoleName, and its value must be the name of the IAM role created by the template. StackSets uses this output to validate that the role name the template provisioned matches the ExecutionRoleName you passed when you created or updated the stack set. If the output is missing or the key is misspelled, the template fails validation.
4. No nested stacks or transforms
The template must not include:
- Nested stack resources (
AWS::CloudFormation::Stack). - CloudFormation transforms, such as
AWS::Serverless-2016-10-31or custom macros.
A working example
The following least-privilege template creates an execution role scoped to S3 bucket operations on buckets matching a naming prefix, plus the CloudFormation actions StackSets needs to drive stack operations in the member account.
This template is an illustrative example. The cloudformation:* permissions on all resources are the minimum StackSets needs to drive stack operations in each member account. Narrowing them below this can cause stack operations to fail. Adjust the S3 statement to match the resources your workload uses.
Replace 123456789012 with your management account ID. Using !Ref on the role returns the role name dynamically, so you don’t need to repeat it in the output.
Creating a StackSet with a custom execution role template
Supply the template to CreateStackSet in one of two ways:
ExecutionRoleTemplateBody– the template body as an inline string (JSON or YAML).ExecutionRoleTemplateUrl– the Amazon Simple Storage Service (Amazon S3) URL of the template file.
Specify either one of these. If you provide both, the operation returns an error.
Figure 1: Console view of the configurable options when creating a StackSet custom execution role
Using the AWS CLI
The --execution-role-name value must match the RoleName in your execution role template, and it must start with stacksets-exec-custom-. StackSets validates this prefix and returns an error if it does not match.
Custom execution role templates always require CAPABILITY_NAMED_IAM. This flag acknowledges that the templates create named IAM resources. The execution role template always creates a named IAM resource, because it must use the required stacksets-exec-custom- prefix through an explicit RoleName. If your workload template also uses transforms (such as AWS::Serverless-2016-10-31) or macros, add CAPABILITY_AUTO_EXPAND as well. Capabilities apply at the stack set level and pass down to each stack instance.
With an S3-hosted template:
Note: If you use an S3 URL, your credentials must have read access to the S3 object. The URL can be in path style (https://s3.amazonaws.com/my-bucket/key.yaml) or virtual-hosted style (https://my-bucket.s3.region.amazonaws.com/key.yaml).
Using the CloudFormation console
The create StackSet wizard defaults to Use default execution role, which is the AdministratorAccess role. To attach a custom execution role, select Set execution role and either paste an S3 URL or upload a local template file.
The console also asks for an IAM execution role name in a separate field. StackSets uses the name you enter in this field as the execution role name, not the RoleName value in the template. Make sure the name in the field still starts with the required stacksets-exec-custom- prefix.
Figure 2: The StackSet creation wizard defaulting to the AdministratorAccess execution role, with the option to set a custom execution role
Updating the execution role template
To update the execution role template for an existing stack set, call UpdateStackSet with a new ExecutionRoleTemplateBody or ExecutionRoleTemplateUrl. The same validation requirements apply. When you update the execution role template, StackSets updates the role on every existing stack instance. You can’t specify deployment targets in the same call.
The --execution-role-name value is required only when you transition from the default execution role to a custom execution role. On subsequent updates to the execution role template, it’s optional.
On the console, you can also change the execution role name without replacing the template. Select the Use current execution role tile to keep the existing template, and enter a new role name in the IAM execution role name field.
Figure 3: Keeping the current execution role template and changing only the execution role name
On the console, choose the Replace current execution role tile and either paste an S3 URL or upload a new template file.
Figure 4: Replacing the execution role template by providing an S3 URL or uploading a local template file
Setting up an output bucket
StackSets always stores the validated execution role template in a service-owned bucket. You can also configure a bucket you own, and StackSets writes a copy of the template there. This is useful when you want direct visibility into the stored template.
To configure a custom output bucket:
- Create an S3 bucket in the same Region as your stack set.
- Update the bucket policy to allow the CloudFormation service principal (
cloudformation.amazonaws.com) to performs3:PutObjecton the bucket path. - Pass the bucket name using
--stack-set-output-bucketoncreate-stack-setorupdate-stack-set. - StackSets writes the copy at
s3://<bucket>/aws-cloudformation-stacksets/<stack-set-id>/output.json, where the colons in the stack set ID are replaced by periods.
Reverting to the default execution role
To revert a StackSet to the default AdministratorAccess execution role, set UseAdminExecutionRole to true:
Reverting switches StackSets back to the default AdministratorAccess execution role, but it does not remove the custom execution role or its bootstrapping stack from member accounts. There is no automated cleanup today. Delete them manually in each member account if you no longer need them.
On the console, choose the Use default execution role tile during update.
Figure 5: Reverting to the default AdministratorAccess execution role by selecting the Use default execution role tile when updating a stack set
Viewing the current execution role template
Call DescribeStackSet to see the configured execution role template. If an output bucket is configured, the response includes the StackSetOutputBucketPath field, which points to the stored template in S3.
On the console, go to StackSet details, and under StackSet info expand Execution role template. The View in S3 button opens the stored template in a new tab. During update, the Use current execution role tile shows the template currently in use.
Figure 6: The StackSet info tab showing the configured execution role template, where the View in S3 button opens the stored template in a new tab
If you configure a custom output bucket, StackSetOutputBucketPath in the DescribeStackSet response is configuration. It shows where StackSets writes the output file, not whether the write succeeded. Check S3 directly to confirm the object is present.
Common validation errors
CreateStackSet and UpdateStackSet validate your execution role template against the preceding requirements and return a ValidationException when something doesn’t match. Most error messages restate a requirement: more than one resource, a missing output key, a role name that doesn’t start with stacksets-exec-custom-, and so on. Three are easier to miss:
- The account ID in the trust policy principal Amazon Resource Name (ARN) must be your organization’s management account, even when you’re using a delegated administrator.
- The IAM role in the template must not set a
Pathproperty (other than /). This requirement isn’t obvious from the role’s shape. - When you update the execution role template, you can’t also specify deployment targets. StackSets always reprovisions the role in every existing stack instance.
For the full list of error strings and causes, see the Troubleshooting section of the User Guide.
If the execution role stack fails to create in a specific member account, that account’s stack instance deployment fails. Other accounts in the same deployment aren’t affected. Check the stack events in the failing member account for details, then retry by creating new stack instances for those accounts.
Get started
With custom execution role templates, you can keep the cross-account convenience of StackSets while bringing your permissions in line with least-privilege guidance. To learn more about the service, see the AWS CloudFormation product page.
Related resources
- AWS CloudFormation StackSets concepts.
- Prerequisites for StackSet operations.
- Minimum execution role permissions.
- AWS::IAM::Role.
- Activate trusted access with AWS Organizations.
About the authors
Track AWS CloudFormation StackSets deployments with progress visibility
Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/track-aws-cloudformation-stacksets-deployments-with-progress-visibility/
Today, AWS CloudFormation StackSets adds deployment progress visibility, a stage-by-stage view of where each stack set operation stands. You can see how much work is complete, and which accounts and stack instances need attention. Whether you target tens of accounts or thousands, you can follow a deployment while it runs and act on results without waiting for it to finish.
With AWS CloudFormation, you model and provision your cloud infrastructure as code, writing templates in JSON or YAML or generating them with tools like the AWS Cloud Development Kit (CDK). CloudFormation StackSets extends this to many accounts and AWS Regions. With a stack set, you can deploy the same template, such as a networking baseline or security controls, to every account and Region you target in one operation. Each deployment of the template to one account and Region is a stack instance. With service-managed stack sets, StackSets works with AWS Organizations to provision the access it needs in each target account for you.
In this post, we’ll explore how to read deployment progress on the CloudFormation console and through the API. Whether you’re a platform engineer rolling out an organization-wide baseline or a developer building automation around StackSets, we’ll show you how to:
- Follow a large deployment as it moves through each stage.
- Find out why a deployment that reports success did not deploy any stacks.
- Check progress from scripts and automation.
- Review how each stage ended after the deployment completes.
The walkthrough shows how stage-level progress gives you confidence that a rollout is on track at every stage.
Key capabilities
Deployment progress adds the following to stack set operations that start after launch.
- Two stages for every operation. Each stack set operation reports role provisioning and stack deployment separately, each with its own status and percentage complete.
- Counts for each stage. Role provisioning reports accounts that succeeded, failed, completed, and are pending. Stack deployment reports stack instances that succeeded, failed, completed, are pending, were skipped, and were cancelled.
- Progress for each Region. The console shows a Deployment by Region table, and describing an operation returns stack deployment progress for each Region.
- Results after completion. Progress remains available after the operation finishes. You can review how each stage ended at any time.
- Additive API change. The new fields are additive. Existing integrations continue to work without changes.
How it works
When you start a stack set operation, its overall status works as it does today. Deployment progress adds detail under StatusDetails.Stages in the DescribeStackSetOperation and ListStackSetOperations responses, and on the Progress tab of each operation on the CloudFormation console. The stage statuses are separate from the overall operation status.
To open it on the console, choose View progress report for an operation on your stack set’s Operations tab. If the operation’s details page is already open, choose the Progress tab.
The following image shows the Operations tab for a stack set. The View progress report link for a completed CREATE operation is highlighted in the Actions column.
Figure 1: Choose View progress report for an operation on the Operations tab
The following image shows the details page for the same operation while it was running, with the Progress tab highlighted next to the Stack instances tab.
Figure 2: Alternatively, on an operation’s details page, choose the Progress tab
The Progress tab has up to three sections. Role provisioning shows the status and the succeeded, failed, pending, and total account counts. Deployment shows the status and the succeeded, failed, pending, cancelled, skipped, and total stack instance counts. Deployment by Region shows the same stack instance counts for each Region, and notes whether Regions are processed one at a time or in parallel. While an operation runs, a progress bar shows the Deployment percentage complete. When the operation finishes, the stage status replaces the progress bar. For operations on a self-managed stack set, the console leaves out the Role provisioning section and shows only Deployment and Deployment by Region. For other operations that don’t provision roles, such as updates, the Role provisioning section shows NOT_APPLICABLE. The completed count appears only in the API response, where it is the sum of succeeded, failed, skipped, and cancelled.
Role provisioning prepares access in each target account of a service-managed stack set. When StackSets has resolved the target accounts, the stage reports counts of succeeded, failed, completed, and pending accounts, and its percentage complete. In the API response, operations that don’t provision roles, including operations on self-managed stack sets, report this stage as NOT_APPLICABLE.
Stack deployment deploys your template as a stack instance in each account and Region. It begins after role provisioning finishes, and its counts appear once the stage starts. Two counts tell you why a stack instance was not deployed:
- Skipped stack instances belong to accounts that did not complete role provisioning, or to suspended accounts. Because an operation has one stack instance per account in each Region, 4 accounts that did not complete role provisioning in a 3-Region operation give 12 skipped stack instances.
- Cancelled stack instances were not attempted because the operation exceeded its failure tolerance or was stopped.
Completed is the sum of succeeded, failed, skipped, and cancelled, and pending is the total minus completed. The percentage complete is completed divided by total, rounded down to the nearest tenth. There is no separate in-progress count. StatusDetails also reports the total number of target accounts and stack instances once StackSets has resolved the operation’s targets.
Each stage reports one of these statuses: NOT_APPLICABLE, NOT_STARTED, IN_PROGRESS, SUCCEEDED, PARTIAL_SUCCESS, or FAILED. The two stages can end differently. For example, role provisioning can end in PARTIAL_SUCCESS while stack deployment ends in SUCCEEDED, because stack deployment succeeded for every stack instance that was not skipped.
Behavior by operation type
| Operation | Role provisioning | Stack deployment |
| Create operations on a service-managed stack set, including auto-deployments | Reported | Reported |
| Update and delete operations on a service-managed stack set, and all operations on a self-managed stack set | NOT_APPLICABLE |
Reported |
| Drift detection | NOT_APPLICABLE |
NOT_APPLICABLE |
This table reflects behavior at launch. To write automation that keeps working as StackSets adds features, read the role provisioning status in each response rather than inferring it from the operation type.
DescribeStackSetOperation includes stack deployment progress for each Region in RegionalStatusDetails. ListStackSetOperations returns the overall stages without the regional breakdown. Both stage progress and the Regional breakdown remain available after the operation finishes.
Scenario 1: Follow a large deployment as it runs
You’re a platform engineer rolling out a baseline from a service-managed stack set to 240 accounts in 3 Regions, which is 720 stack instances. The operation has been running for about 20 minutes and you want to know how far it has come.
On the console
- Open the CloudFormation console and choose StackSets.
- Choose your stack set, then choose the Operations tab.
- Choose View progress report for the running operation.
The following image shows the Progress tab for the operation while it runs, with the Deployment progress bar at 90 percent and progress for each Region.
Figure 3: Progress tab for a running operation
The overall status is still RUNNING, and the Progress tab shows what that status covers. Role provisioning has succeeded for all 240 accounts. The Deployment progress bar is at 90 percent, with 651 stack instances succeeded, none failed, and 69 pending. Deployment by Region shows the status for each Region. The US East (N. Virginia) Region (us-east-1) is done, the Europe (Ireland) Region (eu-west-1) has 5 stack instances pending, and the US West (Oregon) Region (us-west-2) has 64 pending. You can let the operation continue with confidence that it is progressing.
With the AWS Command Line Interface
Sample output (abbreviated):
The API reports the percentage rounded down to the nearest tenth (651 of 720 is 90.4 percent). The console progress bar shows 90%.
Scenario 2: Find out why nothing deployed
You start a create operation that targets 4 accounts in 3 Regions, which is 12 stack instances. The operation finishes in seconds with an overall status of SUCCEEDED, but no stacks appear in the target accounts.
The following image shows the Progress tab after the operation finished. Role provisioning shows FAILED for all four accounts, and Deployment shows SUCCEEDED with all 12 stack instances skipped.
Figure 4: Progress tab after role provisioning failed in every target account
The Progress tab shows what happened. Role provisioning is FAILED, with all 4 accounts failed. Deployment is SUCCEEDED because no stack instance failed, but all 12 stack instances are skipped. Deployment by Region shows 4 skipped stack instances in each Region. Role provisioning did not complete in any account, so StackSets had nothing to deploy. In this example, all four target accounts were suspended.
Sample output (abbreviated):
To see the status reason for each account, list the operation’s results:
Your next step is to review the affected accounts, for example confirming whether they are active in AWS Organizations, and then run the operation again for them.
Scenario 3: Check progress from scripts and automation
You run StackSets operations from a pipeline and want a short progress line in your build logs. ListStackSetOperations returns the same stage details for recent operations, without the Regional breakdown:
For one operation, you can extract the stack deployment percentage directly:
Sample output, for the operation in Scenario 1:
For operations that start after launch, every stage is present in the response, with NOT_APPLICABLE or NOT_STARTED when it is not active. Your automation reads the same structure for every operation type. AI agents that call the CloudFormation API on your behalf can read the stage status to tell whether a stage is active. Operations that ran before launch don’t include Stages in their response, so check that the field exists before you read it, for example when you list older operations.
Scenario 4: Review how each stage ended
The operation from Scenario 1 has finished. You want to confirm the result before you move on.
The following image shows the Progress tab after the operation completed, with both stages and all three Regions showing SUCCEEDED.
Figure 5: Progress tab for the completed operation
The overall status is SUCCEEDED. Role provisioning succeeded for all 240 accounts. Deployment shows SUCCEEDED in place of the progress bar, with all 720 stack instances succeeded and none failed, pending, cancelled, or skipped. Deployment by Region shows 240 succeeded stack instances in each of the 3 Regions. Because progress remains available after the operation finishes, you can come back to these results later.
Best practices
- Use the counts to decide your next step. Failed stack instances point to the template or the resources it creates. Skipped stack instances point to role provisioning, or a suspended account. Cancelled stack instances point to the failure tolerance, or a stopped operation.
- Check role provisioning and the overall status. If role provisioning fails for every target account, StackSets skips every stack instance. As Scenario 2 shows, stack deployment and the overall operation still report
SUCCEEDED, even though no stacks were deployed. AFAILEDrole provisioning status with a skipped count equal to the total tells you this happened. - Use
DescribeStackSetOperationwhen you need the Regional breakdown, andListStackSetOperationsfor a quick view across recent operations. - Treat
NOT_APPLICABLEin the API response as expected for the operation type, for example role provisioning on self-managed stack sets or both stages for drift detection. - Totals and pending counts appear only after StackSets resolves the operation’s targets. Handle their absence early in an operation, and for operations that ran before launch, which don’t include
Stages.
Getting started
Deployment progress is available at no additional charge in all AWS Regions where CloudFormation StackSets is supported. On the CloudFormation console, choose View progress report for a stack set operation on the Operations tab. You can also call DescribeStackSetOperation or ListStackSetOperations with the AWS Command Line Interface (AWS CLI) or AWS SDKs. To use the new fields from the command line, use AWS CLI version 2. They are not available in AWS CLI version 1. In code, use an AWS SDK version released on or after November 18, 2026.
Conclusion
Deployment progress shows where each StackSets deployment stands, stage by stage and Region by Region. You can follow a rollout across thousands of accounts, find the accounts and stack instances that need attention while it runs, and review how each stage ended afterward. Existing integrations continue to work without changes.
For a full description of each stage, status, and count, including how they differ by operation type, see Monitor StackSet operation progress in the AWS CloudFormation User Guide. If you’re building automation, the DescribeStackSetOperation and ListStackSetOperations pages in the AWS CloudFormation API Reference list every new response field. To learn more about modeling and provisioning infrastructure as code across accounts and Regions, visit the AWS CloudFormation product page.
About the authors
How Klaviyo processes 3 billion daily events at scale with Amazon MSK Express
Post Syndicated from Jonathan Li original https://aws.amazon.com/blogs/big-data/how-klaviyo-processes-3-billion-daily-events-at-scale-with-amazon-msk-express/
Klaviyo (NYSE: KVYO) is an autonomous business-to-consumer (B2C) customer relationship management (CRM) platform used by more than 200,000 brands to understand and act on customer relationships in real time. Every personalized email, SMS, and push notification that Klaviyo sends depends on a streaming pipeline that ingests roughly 3 billion events per day. These events range from email opens and website visits to purchase completions and cart abandonments.
In this post, we share how Klaviyo migrated from RabbitMQ to Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers. We also show how Amazon MSK Express let a small team scale its event pipeline ahead of Black Friday/Cyber Monday (BFCM) 2025. With Amazon MSK Express, Klaviyo delivered more than 22.7 billion messages, up 25 percent year over year, and scaled back down afterward over a five-day period.
The challenge
Events are the lifeblood of Klaviyo’s platform. Every customer interaction flows through the streaming pipeline. Klaviyo’s previous RabbitMQ-based event infrastructure supported the platform through years of rapid growth. As volume climbed, scaling it beyond a certain point became increasingly difficult, so the team set out to build a foundation for the next stage of scale, with three requirements:
- Absorb extreme bursts – BFCM drives roughly 7 times normal event volume, concentrated into five days.
- Serve two service level objective (SLO) classes on one pipeline – Real-time triggers (5-second SLO) and analytics aggregates (20-minute SLO) share infrastructure, so slower work can never hold up time-critical events.
- Zero data loss – Every event is a customer interaction that drives personalized marketing, so nothing can be silently dropped.
The replacement had to sustain peaks of 170,000 events per second, absorb a 7 times spike, and scale back down afterward.
Solution overview
Klaviyo rebuilt its event gateway infrastructure on Apache Kafka, choosing Amazon MSK Express brokers as its fully managed streaming backbone serving as the front door for all inbound events.
Figure 1: Klaviyo’s event gateway architecture on Amazon MSK Express, showing the gRPC publisher, p10/p20/p30 priority topics, the Kubernetes orchestrator, retry topics and dead-letter queue, Amazon S3 failure capture, and a second gateway cluster in eu-central-1
The solution includes the following key components:
- Event gateway cluster – The entry point for all inbound events (email opens, clicks, site activity, API calls), running on express.m7g.4xlarge brokers in the US, with a second cluster in the EU.
- Three-tier priority topics – Events are routed to priority topics (p10, p20, p30) with 360 partitions each. The partition count is set by the consumer topology rather than the broker count: the event orchestrator runs as StatefulSets with one pod per partition, which comes to 90 pods in each of four Kubernetes clusters and 360 pods in total.
- Graduated retry architecture – Five retry delay levels with exponential backoff, plus a dead-letter queue, so no event is silently dropped.
Priority-based event processing
Rather than treating all events equally, Klaviyo routes events to priority tiers through a gRPC publisher proxy. This design degrades gracefully under extreme load. High-priority events (such as purchase confirmations that trigger transactional flows) are processed first, while lower-priority events (such as batch analytics updates) can tolerate higher latency.
Critically, Klaviyo runs one unified set of processors across all three priority levels instead of standing up separate infrastructure per level. That consolidation cut costs by roughly 30 percent through improved resource utilization. For the design in depth, see Building a Distributed Priority Queue in Kafka.
Resilient event publishing
Klaviyo designed its event publisher to survive failure at every layer. A publish that fails against one Kafka cluster has several fallback mechanisms to make sure that there will be no permanent data loss. Most failures recover automatically, and the rest are preserved for replay. Over one three-month window, roughly 20,000 events were recovered without human intervention, out of approximately 300 billion processed in that period.
Klaviyo also retains seven days of event history for replay in the case of downstream incidents.
For more on Klaviyo’s eventing design, see Rebuilding Event Infrastructure at Scale and Building a Resilient Event Publisher with Dual Failure Capture.
Scaling for Black Friday with MSK Express
The clearest demonstration of this architecture came during BFCM 2025, the largest ecommerce event of the year, when the pipeline carried the traffic behind Klaviyo customers’ most revenue-critical campaigns across five consecutive days.
The scale-out timeline
| Period | Brokers | Context |
| Steady state (through September 2025) | 12 | Normal daily processing of ~3B events |
| Early October 2025 | 18 | First capacity increase ahead of the holiday season |
| Late October–November 2025 (BFCM) | 60 | Full Black Friday / Cyber Monday capacity |
| December 2025 (post-BFCM) | 18 | Optimized steady-state fleet |
The team scaled the event gateway cluster up several-fold over about seven weeks, held it through Cyber Monday, then scaled it back down in December.
Why MSK Express made this possible
Three capabilities of MSK Express were critical to making this operational with a lean team.
No storage provisioning – Express brokers remove storage sizing and provisioning entirely. You pay for the data ingested into the cluster and the data stored in it, per GB per hour, and all stored data is replicated across three Availability Zones for high availability. This pay-as-you-go model eliminates wasted capacity costs. For Klaviyo, it meant a large holiday scale-out required no storage capacity planning at all.
Intelligent Rebalancing – Adding brokers to an Apache Kafka cluster normally means redistributing partition data across the new brokers, which traditionally requires careful manual planning, monitoring, and throttle management. MSK Express Intelligent Rebalancing automates that redistribution without manual intervention or performance degradation, and AWS reports that Express brokers rebalance partitions 180 times faster than Standard brokers. For Klaviyo, this meant adding brokers at scale for BFCM without an engineer owning partition reassignment at scale.
Built-in high availability – Based on AWS internal testing, Express brokers recover from failure 90 percent faster than Standard brokers, thanks to storage improvements. A replacement node starts up with almost no disruption to the rest of the cluster, rather than triggering a significant rebalance. Express brokers are also highly available by default, with the service managing the critical cluster and topic configurations that would otherwise need hand-tuning.
Results
Since migrating to Amazon MSK Express, Klaviyo has achieved the following results:
- Multi-fold broker scale-out in under two months to absorb BFCM peak traffic, with a clean scale-down afterward.
- Approximately 30 percent cost reduction from running unified processors across all three priority levels instead of separate infrastructure per level.
- 5-second SLO held for real-time event triggers at a peak of 170,000 events per second.
- 22.7 billion messages delivered over BFCM 2025, up 25 percent year over year.
- Multi-Region since May 2026, with a second event gateway cluster in eu-central-1 serving European customers.
- MSK Express adopted across Klaviyo’s event gateway clusters in both US and EU AWS Regions.
As Klaviyo’s engineering team wrote in Rebuilding Event Infrastructure at Scale:
“Moving to managed Kafka infrastructure on AWS MSK was one of those decisions that keeps paying dividends.”
It freed up engineers to spend their time building features rather than operating messaging infrastructure.
Key learnings
Based on Klaviyo’s experience building and operating this architecture, here are key takeaways for teams considering a similar approach:
- Design for extreme elasticity from day one – Klaviyo’s BFCM traffic drives a multi-fold surge in event volume into five days. Designing partition layouts, topic structures, and consumer groups to accommodate elastic scaling before you need it avoids painful re-architecture under pressure.
- Size partitions for your consumers, not your brokers – Klaviyo’s 360 partitions per topic come from its consumer topology (one orchestrator pod per partition), which stays fixed while the broker fleet scales up and back down underneath it. Coupling partition count to broker count would have forced a partition change in the middle of the holiday ramp.
- Scale down as deliberately as you scale up – Klaviyo returned to a right-sized fleet after BFCM rather than carrying peak capacity all year. Because Express bills storage per GB rather than per provisioned volume, scaling down left no stranded storage cost behind.
- Run multiple SLO classes on one pipeline – A single set of processors serves all three priority tiers, which cut costs by roughly 30 percent. Priority routing still protects latency: real-time triggers held their 5-second SLO at a peak of 170,000 events per second.
- Build fault tolerance into every layer – Cross-cluster failover, a dead-letter queue, and an Amazon Simple Storage Service (Amazon S3) fallback mean individual failures don’t cause data loss. Express broker recovery keeps a lost broker from turning into a cluster-wide disruption.
Conclusion
Klaviyo’s journey from RabbitMQ to Amazon MSK Express demonstrates how a managed streaming service helps high-growth companies operate mission-critical event infrastructure at massive scale without proportionally growing their operations team. By combining MSK Express Intelligent Rebalancing with thoughtful architecture design (priority-based topics, graduated retry queues, and layered failure capture), Klaviyo’s lean infrastructure team scaled 5 times during the largest ecommerce event of the year.
Klaviyo’s use of Amazon MSK has since grown beyond the event pipeline. Its change data capture (CDC) infrastructure now runs on Amazon MSK Express as well. The team is also evaluating migrating its remaining self-managed Apache Kafka clusters on Amazon Elastic Compute Cloud (Amazon EC2), which serve data lake workloads, to MSK.
If you’re operating Apache Kafka workloads that require elastic scaling, operational simplicity, or both, consider Amazon MSK Express brokers for your next streaming workload.
About the authors
How Country Road Group built a pattern-driven integration solution on AWS
Post Syndicated from Aman Sharma original https://aws.amazon.com/blogs/architecture/how-country-road-group-built-a-pattern-driven-integration-solution-on-aws/
Are you an integration architect, platform lead, or engineering manager spending a considerable amount on middleware licenses only to move data between systems? This post shows how Country Road Group replaced that middleware with a pattern-driven integration solution on AWS.
Enterprise integration solutions like BizTalk, MuleSoft, TIBCO and Boomi solved the right problem when they emerged. But they also tightly coupled applications to the middleware itself, through proprietary adapters, orchestrations, and message formats. That coupling has become a major source of cost and pain. Many organizations now pay hundreds of thousands per year in licensing, hosting, and maintenance for middleware that delivers no new capability. Meanwhile, the talent to maintain it disappears from the market. The interfaces themselves haven’t changed: publish-subscribe, content-based routing, request-reply, scatter-gather. Cloud-native services now implement them directly, without requiring a middleware runtime in between.
Country Road Group (CRG) is a major Australian fashion retailer operating five brands (Country Road, Mimco, Witchery, Politix, and Trenery) across more than 600 stores. CRG faced exactly this problem. Their 21 integration interfaces ran on Microsoft BizTalk Server hosted on VMware, connecting point-of-sale systems, Oracle RMS databases, and ecommerce platforms. BizTalk was approaching end-of-support. VMware costs were escalating post-Broadcom acquisition. And the team couldn’t hire BizTalk developers anymore.
In this post, we walk through CRG’s Strategic Integration Platform (SIP) and the declarative, pattern-led approach behind it. Rather than writing orchestration code for each interface, CRG’s teams declare which integration pattern an interface uses, and pre-built Terraform modules provision the infrastructure behind it. We cover the four processing lanes that replaced BizTalk and the custom Error Management System that handles failures across them.
The approach doesn’t depend on any one infrastructure-as-code tool. To help your team adopt it, we’re also releasing a starter kit: the Enterprise Integration Patterns AWS Cloud Development Kit (AWS CDK) Library. It’s an open-source set of 29 constructs that implement the same patterns as reusable infrastructure. Teams using Terraform can use it as a reference implementation. The kit includes an agent skill that helps AI coding assistants such as Kiro and Claude Code select, configure, and compose the right pattern.
Why CRG built SIP
CRG’s existing integration ecosystem suffered from tool sprawl and the presence of end-of-life middleware (BizTalk 2013), leading to increased production instability and operational overhead.
SIP addressed four key value drivers
Legacy debt: Decommission BizTalk 2013 and its unsupported VMware/Broadcom infrastructure.
Tool sprawl: Consolidate BizTalk, Workato, Apollo, and Kafka into a single integration solution with one engineering skillset.
Low velocity: Adopt API-first and continuous integration and continuous delivery (CI/CD) patterns to accelerate new partner integrations.
Security and resiliency risk: Standardize authentication and authorization across every interface and treat dead-letter queues (DLQs) as data stores. Failed messages hold full copies of customer payloads, so DLQs need the same encryption, retention, and access controls as the primary channel to stay within data residency and retention requirements.
SIP architecture overview
The SIP follows a “Compose on Cloud-Native” strategy. It combines AWS serverless compute (Spring Boot on AWS Lambda, AWS Step Functions, Amazon EventBridge) with Apache Camel on Amazon Elastic Container Service (Amazon ECS) with AWS Fargate for long-running and stateful flows.
The architecture is organized into three layers as shown in Figure 1: a pattern layer where each interface is composed from standardized integration patterns, an AWS service layer where Terraform and CI/CD templates provision and govern infrastructure, and a source-and-target connectivity layer bridging on-premises, cloud, and B2B endpoints.
Traffic flows through a four-lane, pattern-led service bus (batch, API, JDBC, and event), as shown in Figure 2. Each lane routes to the appropriate compute runtime based on payload characteristics and processing duration.
Figure 1: CRG strategic integration solution — key building blocks
- Pattern layer: Each of the 21 interfaces is expressed as a composition of standardized integration patterns (publish-subscribe, content-based routing, and others). This layer contains the business-specific logic: Lambda handlers that validate, transform, and route payloads, orchestrated by Step Functions for multi-step workflows and triggered by Amazon EventBridge rules or Automic. The patterns act as a shared vocabulary across the engineering team. Deployment of an interface starts by selecting a declarative pattern or Terraform code, not by writing infrastructure from scratch.
- AWS service layer: The solution provisions its integration surface from AWS managed services, grouped by role. Amazon API Gateway is the entry point, with AWS WAF shielding and rate limiting in front. AWS Lambda handles stateless event processing, and AWS Step Functions orchestrates multi-step workflows with standardized retry and catch logic. Amazon EventBridge is the canonical event bus, with Amazon Simple Queue Service (Amazon SQS) and Amazon Simple Notification Service (Amazon SNS) providing asynchronous buffering and fan-out. Amazon Simple Storage Service (Amazon S3) persists messages, using S3 Intelligent-Tiering and archival to Amazon S3 Glacier storage classes. AWS Transfer Family provides managed SFTP and FTP endpoints. Amazon ECS with AWS Fargate runs Apache Camel routes for long-running flows, and Amazon DynamoDB holds metadata and the error index. Terraform is the authoritative provisioning engine for every AWS resource.
- Source and target connectivity layer: On the source side, SIP integrates with on-premises, OCI, legacy core applications (Oracle RMS, Manhattan WMS, Magenta Retail), cloud and digital platforms (Salesforce Service Cloud, eStar Online), and B2B partner portals. On the target side, flows deliver to Oracle databases, eStar (ecommerce), file systems, and partner endpoints.
Note: SIP pulls. Sources don’t push. SIP retrieves data from source systems on its own schedule rather than accepting unbounded pushes. The consumer, not the producer, controls the rate. Where pull doesn’t fit: Some sources can only push, such as SaaS webhooks. In those cases, SIP accepts the push into a queue and processes it at its own pace, so the same principle holds.
Figure 2: CRG Strategic Integration Platform — multi-lane service bus architecture showing four processing paths (batch, API, JDBC, event) with transformation routing and error management
SIP routes traffic through four pattern-led lanes
- Lane 1 (MFT/Batch) handles file-based ingestion: Automic or Amazon EventBridge triggers AWS Transfer Family to receive SFTP traffic, archive to S3, and hand off to a parser Lambda for validation and transformation.
- Lane 2 (API/Real-Time): Processes synchronous REST requests through Amazon API Gateway into a Step Functions orchestrator. A transformation engine routes to the appropriate runtime: Lambda for sub-five-minute jobs, or Apache Camel on ECS Fargate for long-running and stateful flows.
- Lane 3 (JDBC/Data Aggregator): This pattern handles direct database connectivity for bulk extractions, routing through Lambda and Amazon AppFlow for lightweight aggregation or ECS Fargate for heavier workloads.
- Lane 4 (Event/Message) manages asynchronous flows: External events enter through API Gateway while internal events route through Amazon EventBridge, with Amazon SNS for fan-out broadcasting and Amazon SQS for buffered consumption.
Across all four lanes, the Error Management System (EMS) provides a unified error handling layer. Failed transactions route to a dead letter queue in Amazon SQS. EMS captures the error metadata in DynamoDB and persists the payload in Amazon S3, with every failure carrying a correlation ID and a standardized JSON error contract. It is built on Spring Boot running on Lambda, with a Next.js front end on AWS Amplify.
L1 and L2 operators use the EMS dashboard to inspect, modify, and resubmit failed transactions idempotently, without developer involvement. New interfaces onboard to EMS automatically through a unique interface ID. This moved CRG from developer-led (L4) error recovery to operator-led (L1) first-line resolution.
Key design decisions
Lambda-first, ECS as fallback: Lambda handles short-duration event processing, Apache Camel on ECS Fargate serves long-running, stateful, and large-file flows.
Reproducible infrastructure: Every AWS resource in the platform is defined in Terraform, so any environment can be rebuilt exactly from code. That fixes configuration drift, a bad change, or an accidentally deleted resource, and the same templates stand up a new environment or Region. Terraform state is held in a versioned, access-controlled S3 bucket. Infrastructure as code rebuilds the platform, not its data, so data is protected separately. DynamoDB point-in-time recovery restores tables, S3 versioning restores objects, and dead-letter queues hold failed messages for redrive. Runtime failures such as an Availability Zone outage don’t need a redeploy at all, because Lambda, SQS, DynamoDB, and Step Functions run across multiple Availability Zones by default.
Amazon EventBridge as canonical event bus: All inter-pattern communication flows through Amazon EventBridge for content-based routing, event replay, and native integration with over 200 AWS services.
Five-layer security: AWS Identity and Access Management (IAM) least-privilege role-based access control (RBAC), AWS WAF with virtual private cloud (VPC) isolation, data classification (Public through Restricted), TLS 1.2+ in transit with AWS Key Management Service (AWS KMS) encryption at rest, and structured audit logging with automated personally identifiable information (PII) redaction.
Open source: Enterprise Integration Patterns CDK Library
In this post, we share an open-source AWS CDK construct library that codifies 29 canonical integration patterns as reusable L3 constructs. Each construct provisions messaging infrastructure, IAM permissions, dead-letter queues, and retry logic from a single declaration. Amazon CloudWatch alarms are deliberately left to the consumer, because thresholds and notification targets are environment specific. The library uses TypeScript and AWS CDK. Teams using Terraform or other infrastructure as code tools can reference the patterns and translate to their provisioning framework.
Prerequisites
An AWS account with the AWS CDK bootstrapped in your target AWS Region, Node.js 20 or later, and the AWS CDK CLI v2. Familiarity with TypeScript helps but the examples are short. For Path 2 you also need Kiro or Claude Code.
Getting started
There are two ways to go from a requirement to a deployed pattern. Path 1 is hands-on: you write the construct declaration and run the CDK commands yourself. Path 2 is agent-assisted: the agents shipped in the repository select and configure the construct for you, and you run the final deploy. Both produce the same thing, a small app.ts that instantiates one or more of the 29 library constructs, so the security posture is identical whichever you choose. Start with Path 1 if you already know which pattern you need. Start with Path 2 if you are coming from a legacy platform’s vocabulary and want help mapping it. Both paths begin the same way:
The repository is a construct library, not a deployable application: app.ts ships as an empty stub, and cdk synth on a fresh clone produces no stacks by design.
Path 1: Declare a pattern yourself
Open app.ts and declare the construct you need. The README’s Implementation Guide has worked examples for request-reply, publish-subscribe, scatter-gather, and saga. Then synthesize and deploy:
Path 2: Let the agents do the selection and configuration
Open the repository in Kiro or Claude Code and select an agent from the chat input. Kiro, the agentic coding IDE and CLI from AWS shown in Figure 3, uses spec-driven development to translate natural-language requirements into pattern compositions. Describe the integration requirement in your own terms, and the agent selects the right construct from the library, writes the declaration into app.ts with correctly configured props, and validates it with npm run build, npm test, and cdk synth. Deployment stays with you: the shipped eip-architect agent is denied cdk deploy and cdk destroy by design, so nothing reaches an account without a human running it. When the agent reports the declaration ready, you run the same two commands as Path 1.
The repository ships two agent skills and two custom agents for this. Use them in order, or go straight to the second if you already know what you are building.
integration-advisorruns discovery. It asks the questions, maps each of your existing interfaces to a construct, and writes an assessment file. It touches no code.eip-architectpicks that assessment up and writes the CDK declarations that instantiate the right library constructs with the correct configuration for each pattern, then verifies them.
Figure 3: Two agents in action, integration-advisor and eip-architect, running in the Kiro CLI
Clean up
Remove anything you deployed with npx cdk destroy. The constructs default to RemovalPolicy.DESTROY, so queues, tables, and buckets created by a pattern are removed with the stack.
Results
Annual integration service costs dropped from approximately $300,000 to $60,000, an 80 percent saving. Four middleware tools (BizTalk, Workato, Apollo, and Kafka) consolidated to one. The primary objective, full decommissioning of Microsoft BizTalk Server and its associated VMware/Broadcom infrastructure, has been accomplished. CRG now deploys new interfaces through standardized patterns in hours rather than weeks, using cookie-cutter Terraform templates and automated CI/CD pipelines. The Error Management System shifted failure resolution from engineering to L1 operators, fundamentally changing the support cost model. Distributed telemetry across Amazon CloudWatch, AWS X-Ray, and Dynatrace provides end-to-end transaction tracing with correlation IDs through every integration hop. CRG migrated interfaces in waves grouped by business function, with service-group rollback allowing any failed wave to revert independently. The architecture is cloud-native by design: because the pattern layer is decoupled from the service layer, you can incorporate new AWS services as steps within any existing pattern composition without re-architecting the platform.
Conclusion
For organizations retiring legacy middleware or designing integrations from scratch, the goal is the same: a modern, decoupled architecture where systems exchange data through well-understood patterns, not through a central runtime they all depend on. CRG’s approach offers a replicable playbook. Legacy integration middleware carries compounding costs: licensing, hosting, scarce talent, and opportunity cost from slow delivery cycles. A pattern-driven migration on cloud-native services addresses all four simultaneously. The open-source AWS CDK construct library and Kiro agent skill published alongside this post give your team a head start, packaging the patterns CRG proved in production. Whether you run BizTalk, MuleSoft, TIBCO, or Boomi, the integration patterns are the same. Only the execution layer changes.
About the authors
What’s new in AWS Transform – continuous modernization for re:Invent 2026
Post Syndicated from Nithin Moorthy original https://aws.amazon.com/blogs/devops/whats-new-in-aws-transform-continuous-modernization-for-reinvent-2026/
Since general availability in August 2026, platform teams have used continuous modernization through AWS Transform to keep tech debt from piling up. To see what customers have achieved, read the success stories on the AWS Transform – continuous modernization page.
Ahead of re:Invent 2026, we’re making the experience faster to start, easier to act on, and easier to extend. Setup takes a few steps, each issue shows up once across your estate, and remediations arrive as one pull request per repository. You can now bring your own skills (transformation definitions), have one generated when none fits, and ask chat about your estate or have it act for you. A new integration with AWS Health takes you from a planned lifecycle event (PLE), such as an AWS Lambda runtime reaching end of support, straight to the affected code.
Get started in a few steps
Getting your first findings used to mean creating personal access tokens, configuring AWS Identity and Access Management (IAM) roles, and picking analyses before you saw any findings.
Continuous modernization now connects to GitHub, GitLab, and Bitbucket through OAuth, so there are no tokens to manage. It also creates its execution role for you during onboarding.
As soon as your repositories are connected, continuous modernization recommends analyses for your estate. These include comprehensive tech debt for outdated dependencies and end-of-support runtimes, or modernization readiness for repositories that could move to containers or serverless. You choose which ones to run, and recommended analyses are scheduled by default, so your findings stay current without anyone rerunning them.
Figure 1: The continuous modernization Get started page, which connects your source and turns on recommended analyses.
Figure 2: Recommended analyses scheduled to run automatically after you connect your source.
Start from what AWS Health already knows
AWS Health notifies you about planned lifecycle events (PLEs) that affect your account, such as a Lambda runtime reaching end of support or an Amazon Elastic Kubernetes Service (Amazon EKS) version upgrade. It tells you what’s changing and by when. Continuous modernization now integrates with AWS Health to find and fix the affected code.
Figure 3: Planned lifecycle events from AWS Health, grouped by change deadline
Figure 4: Findings from the AWS Health analysis, each mapped to a recommended transformation
Continuous modernization maps each PLE to the affected repositories and findings. For most PLEs, one remediation covers every affected repository. It applies the matching skill, such as an AWS managed Lambda runtime upgrade, and opens one pull request per repository. The deadline and affected resources stay with the work, so you can track each PLE until it’s cleared.
The integration uses the AWS Health API, which requires AWS Business Support+, AWS Enterprise Support, or AWS Unified Operations. In Regions without these plans, Business, Enterprise On-Ramp, or Enterprise Support also works. For details, see Integrating AWS Health with other systems using the AWS Health API.
Know exactly what to tackle first across your organization
Until now, an issue showed up as a separate finding in every repository it touched, so dozens of repositories using the same deprecated library meant dozens of findings to triage.
Figure 5: The redesigned Findings page grouping each issue with its affected repositories, severity, and recommendation
Continuous modernization now groups findings that share an underlying issue, so each issue appears once with every affected repository listed under it. On the redesigned Findings page, each group shows its severity, scope, safety bar status, and recommended AWS managed transformation or specialized skill. Select the groups you want to fix and choose Create remediation plan.
Resolve issues across your organization in one pass
Until now, each finding was remediated in its own pull request, so a repository with five findings meant five pull requests.
Now you can remediate a group of findings together, whether continuous modernization created the group or you did. It combines each repository’s findings into a single pull request, so app teams review and merge once per repository instead of once per finding.
Figure 6: A remediation plan that combines issue groups into one pass with one pull request per repository
Remediate with your own skills
Most platform teams have standards that no general-purpose tool knows about, such as an approved logging framework, a required security configuration, or an internal API you’re retiring.
You can now run your own skills from the console, alongside AWS managed ones:
- Custom analysis scans your repositories against your rules and reports findings. It runs on AWS managed infrastructure or in your own account.
- Custom remediation applies your skills to resolve those findings. It runs on infrastructure in your own account, such as AWS Batch.
Figure 7: Running a custom analysis and selecting your own transformation definition from the console.
When no skill fits, one gets generated
Between AWS managed skills and your own, most findings have a recommended remediation ready. Most estates still have a long tail, such as an internal framework, an unusual build setup, or a library few others use.
When no skill fits a finding, continuous modernization now generates one, and nothing runs until you review the skill and what it will change. Then you choose one of the following options:
- Use it once to remediate this finding.
- Publish it to the skills registry in your AWS account, so it’s ready the next time the issue appears.
Figure 8: A generated skill shown with its target, approach, and validation for review before anything runs
Ask about your estate in plain language
Not every question fits a filter. In chat, you can ask about your findings, analyses, and remediations in plain language. For example:
- “What changed since the last analysis?”
- “Why did the remediation on checkout-service fail?”
- “Plan my week.” Chat summarizes failed work to unblock, remediations ready to start, and findings with no automated remediation.
Chat can also take action: start or schedule an analysis, start a remediation and check its progress, or dismiss findings in bulk. Every action shows a confirmation card first and runs with your own permissions. To ask about something specific, choose Ask about this on any finding, analysis, or remediation.
Figure 9: Chat answering a question about your estate and offering to start the remediation
Take your results anywhere
You can now download the artifacts from any analysis, such as its report. Share them with stakeholders, keep them as audit and compliance evidence, or feed them into your own dashboards and ticketing tools.
See it in action at re:Invent 2026
Try these new features today, and then join us in Las Vegas to see them live and talk with the team. Choose a session ID for times and repeats.
- MAM230 (breakout): From CI/CD to CI/CD/CM: Continuous modernization for AI-generated code.
- MAM350 (code talk): Continuous tech debt analysis and remediation, from findings to fixes.
- MAM344 (breakout): From migration to continuous modernization: reduce tech debt at scale.
- DVT309 (workshop): Your runtime is being deprecated. Your weekend isn’t.
- DVT323 (chalk talk): Tech debt anonymous: bring your worst code to this chalk talk.
- MAM205 (chalk talk): Move code modernization at scale from one-time to continuous.
- DVT301 (builders’ session): Bring your tech debt: build a custom transformation that fixes it.
Get started
Tech debt builds up one outdated dependency at a time. Continuous modernization now sets up in a few steps, shows each issue once, fixes it in one pull request per repository, and starts from what AWS Health already knows. To get started, use the following resources:
- Try it: Open Continuous modernization in the AWS Transform console.
- Read the docs: Continuous modernization in the AWS Transform User Guide.
- Take the workshop: A hands-on, self-paced continuous modernization workshop.
- Watch the demo: An interactive product walkthrough.
Have an AWS Health event waiting? Open Scheduled changes in the AWS Health Dashboard and choose Upgrade with Continuous Modernization.
About the authors
Announcing in-place upgrades from Standard brokers to Express brokers for Amazon MSK
Post Syndicated from Ankita Mishra original https://aws.amazon.com/blogs/big-data/announcing-in-place-upgrades-from-standard-brokers-to-express-brokers-for-amazon-msk/
Amazon Managed Streaming for Apache Kafka (Amazon MSK) now supports in-place upgrades from Standard brokers to Express brokers. With in-place upgrade, you can modernize your existing MSK Provisioned cluster to Express brokers through a fully managed workflow, designed to minimize application changes while helping to maintain high availability throughout. Express brokers deliver increased stability at higher throughputs, scale up to 20 times faster, and recover up to 90% faster than standard Apache Kafka brokers. The in-place upgrade is a direct path to those benefits. Until now, adopting Express brokers meant standing up a new MSK Provisioned cluster and migrating both your data and your applications to it. That cut-over added weeks or months of cross-team coordination and put application availability at risk. The in-place upgrade removes that work entirely. Amazon MSK modernizes your existing cluster to Express brokers through a fully managed workflow, with no new cluster, no application changes, and no downtime, turning a multi-month migration into a few hours.
With the in-place upgrade, Amazon MSK adds Express brokers to your existing cluster and moves topics for you, preserving both the cluster endpoint and your Kafka topic offsets. As partitions move, MSK reassigns their replicas to the Express brokers and transfers partition leadership through Kafka’s standard leader-election process. Producers and consumers continue using the same topics and the same cluster endpoint without interruption. Applications can continue serving traffic throughout the migration, delivering a zero-downtime client experience. Because the upgrade uses Kafka-native protocols that preserve topic offsets, your stateless and stateful applications (including Apache Flink and Kafka Streams) can resume from their exact position, with no reprocessing, errors, or duplicates. The upgrade can be reversed until you decommission the Standard brokers, keeping you in control throughout the process.
Prerequisites
In-place upgrade to Express brokers is available for MSK Provisioned clusters configured with Standard brokers, in all AWS Regions where MSK Express brokers are supported. Before you begin, confirm your cluster meets the following requirements. These are also validated when you assess upgrade readiness with the API, described in the next section:
- Kafka version: The cluster must run Apache Kafka version 3.9 with KRaft metadata management.
- If it runs an earlier version or still uses ZooKeeper, first upgrade to 3.9 and migrate from ZooKeeper to KRaft. The upgrade keeps your existing Kafka version and KRaft configuration on the Express brokers.
- Refer to In-place ZooKeeper-to-KRaft cluster upgrades for Amazon MSK for more information on upgrading from ZooKeeper to KRaft.
- Three Availability Zones: The cluster must be deployed across three Availability Zones.
- No tiered storage support: Clusters with tiered storage enabled are not supported.
- Topic and broker configuration requirements: Express brokers enforce a set of best-practice configurations to maintain stability and high availability. Before initiating upgrade, confirm your cluster meets the following Express requirements:
replication.factor=3.min.insync.replicas=2.unclean.leader.election.enable = false.segment.msset to at least 60,000 milliseconds.max.message.bytesset to no more than 8 MiB.max.compaction.lag.msset to at least 24 hours.- A supported broker instance type.
- Per-broker partition counts within the Express broker partition quota.
The upgrade process
The following steps use the AWS Command Line Interface (AWS CLI). You can also perform them programmatically with the AWS Management Console or SDK. To perform the upgrade with an AI agent, use the managing-amazon-msk Agent Skill, which powers agents to manage the upgrade process end to end. All sections of this post can be automated with the managing-amazon-msk Agent Skill.
You can upgrade your existing Standard brokers on M5, M7g or M8g instances to Express brokers on M7g or M8g instances. Express brokers on AWS Graviton4-based M8g instances deliver up to 15% lower compute costs, up to 45% lower P99 produce latency, and 2x faster recovery when consumers fall behind, than Express brokers on M7g. You also no longer pay the broker-side cost when moving data across Availability Zones, which reduces total cross-AZ data transfer costs by 50%.
Pre-upgrade: Assess upgrade readiness
To confirm your cluster is ready for in-place upgrade to Express brokers, use the CreateAssessment API. The assessment validates your broker and topic configurations against Express requirements and returns its findings, including any changes to make first. Address any changes that the assessment flags as blockers before you initiate the upgrade. When you initiate the upgrade, MSK automatically re-validates your configuration and proceeds only after all checks pass.
Create the assessment
To create an assessment, specify the target Express instance type. Express brokers are available in the M7g and M8g instance families. You choose the family, and the upgrade keeps your broker size and broker count. For example, if you are on Standard kafka.m5.large, specify express.m7g.large or express.m8g.large. Clusters with Standard brokers on M8g instances can also upgrade to Express brokers on M8g instances:
Check the assessment status
To check the assessment status, use the following and wait until Status shows COMPLETE (assessments typically finish in about two minutes):
List assessment findings
To read the findings after the assessment is complete, use:
ERROR findings are blocking and must be resolved before initiating the upgrade. WARNING and INFO findings are informational. Resolve any blocking findings before continuing.
Performing the upgrade
The in-place upgrade to Express brokers is a managed workflow that you drive at your own pace.
Step 1: Initiate the upgrade
To initiate the upgrade using the CLI, use the UpdateBrokerType API. It takes four inputs:
--cluster-arn, the ARN of the cluster you’re upgrading.--current-version, the cluster’s current version (to get it, use theDescribeClusterAPI).--target-instance-type, a combined string naming your current Standard instance type and the target Express instance type, joined with a hyphen. For example, to upgrade a cluster fromkafka.m7g.largeStandard brokers toexpress.m8g.largeExpress brokers, set the target tokafka.m7g.large-express.m8g.large.--topic-reassignment, how to move topics to Express brokers:- AUTO: Amazon MSK manages the topic migration for you. It validates your configuration, provisions Express brokers matching the count and size of your Standard brokers and moves every topic from Standard to Express in safe, managed batches. Your applications keep producing and consuming against the same cluster endpoint throughout. After all topics are on Express and you have validated your applications, you complete the upgrade to decommission the Standard brokers.
- MANUAL: Amazon MSK provisions the Express brokers but moves no topics until you reassign them yourself, giving you a controlled, topic-by-topic experience. You move and validate topics at your own pace, as described in Step 2.
For example:
Step 2: Move topics (controlled mode only)
When you initiate in controlled mode (--topic-reassignment MANUAL), MSK adds the Express brokers but moves no topics until you drive the reassignments. Wait until the cluster returns to Active with both Standard and Express brokers. Then move topics with the StartTopicReassignment API.
You can selectively move topics with the --topics-to-include and --topics-to-exclude wildcard patterns, and set the direction with --target-instance-type. To move topics to Express brokers, pass your Express instance type ($EXPRESS_INSTANCE, for example express.m8g.large). To move topics back to your Standard brokers, pass your Standard instance type ($STANDARD_INSTANCE, for example kafka.m7g.large). Start with lower-risk topics, validate application performance on Express, then continue.
To complete a migration, all topics (including internal topics) must be moved to the Express brokers. After you finish testing with application topics, confirm you also move internal topics to Express brokers.
Move a specific set of topics onto Express:
For example, to move the orders.* topics to Express brokers:
This moves every topic whose name matches the include pattern onto Express brokers. Patterns are regular expressions, so orders.* can match many topics. It does not name a single topic.
Hold specific topics back from Express:
To move all orders.* topics except the payments topics to Express brokers:
This moves topics such as orders.created and orders.shipped onto Express, and the orders.payments topics stay on Standard. MSK applies the exclude patterns after the include patterns, so a topic that matches both stays where it is. You can move the held-back topics later in a separate reassignment.
Move all topics at once:
You can also move all topics at once to Express brokers. This is useful if you’ve tested a subset of topics on Express, and are ready to complete moving the remaining topics:
This broad include pattern moves every topic, you can narrow the pattern (or exclude) to move topics incrementally.
Stop in-flight reassignment:
To stop a reassignment, you need its topic reassignment operation ARN. The StartTopicReassignment API returns it in the response. You can also get it from the ListTopicReassignments API, which lists every reassignment on the cluster with its operation ARN and status.
Pass the ARN to stop-topic-reassignment:
This stops the in-progress reassignment identified by its operation ARN. Topics that already moved stay on Express brokers. Only one reassignment can run on a cluster at a time, so wait until list-topic-reassignments shows the status as STOPPED. Then start a new reassignment with the same start-topic-reassignment command and patterns you used before. The new reassignment gets its own operation ARN, so use that new ARN if you need to stop it later. To move topics back to Standard instead, set --target-instance-type to $STANDARD_INSTANCE, as shown in the following rollback example.
Roll back process:
To roll back a set of topics by name or wildcard, pass the Standard instance type (for example, kafka.m7g.large) in the --target-instance-type:
Targeting the Standard instance type moves the matching topics back to Standard while the rest stay on Express. Move topics again after the issue is resolved and you’re ready to move the topics back to Express. To roll back all topics from Express brokers to Standard brokers, first use the StartTopicReassignment API with .* as the topic wildcard and your Standard instance type as the target instance type:
Then, decommission the Express brokers by calling UpdateBrokerType with the Standard instance type as the target instance type:
Step 3: Monitor progress
Track the overall upgrade on the Cluster operations tab on the console, or with the DescribeClusterOperation API, passing the operation ARN returned by update-broker-type. In Amazon CloudWatch, graph PartitionCount, BytesInPerSec, and BytesOutPerSec by broker ID to watch partitions and throughput shift from the Standard brokers to the Express brokers.
To check whether the upgrade operation is in progress, complete, or failed, use:
To show migration progress per topic, so you can see which topics have moved to Express and which are still in flight, use:
To list each broker node with its BrokerNodeType, so you can identify which brokers are Standard and which are Express as leadership shifts, use:
The upgrade takes a few hours depending on cluster size and data volume.
Step 4: Validate applications on Express
After every topic has moved to Express brokers, check your workload before you complete the upgrade. The Standard brokers stay in the cluster during this step, so you can still move topics back to them if you find an issue.
To confirm that all partitions have moved, run list-topic-reassignments. Then check that LeaderCount is 0 on every Standard broker. After that:
- Verify that topics, partitions, and consumer groups are present.
- Confirm cluster health:
ActiveControllerCountis 1 andOfflinePartitionsCountis 0. - Confirm producer and consumer throughput and performance align with pre-upgrade baselines.
- Confirm stateful applications (for example, Apache Flink and Kafka Streams) remain healthy and continue processing after partition leadership moves to Express brokers.
If a topic has problems, move it back to Standard with the rollback commands in Step 2. Run this check for at least one full processing cycle of your workload before you continue.
Step 5: Complete the upgrade
MSK waits for you to confirm before it removes the Standard brokers. When your validation is done, choose Complete Upgrade on the console, or call UpdateBrokerType again with only the Express instance type:
Amazon MSK decommissions the Standard brokers, and the cluster returns to the ACTIVE state as an Express-only cluster. This step is final: once the Standard brokers are removed, reverting to Standard requires creating a new cluster and migrating to it with Amazon MSK Replicator. After the upgrade completes, update or retire any monitoring alerts and dashboards that are specific to your former Standard brokers.
Step 6: Post-upgrade optimization
After the upgrade, intelligent rebalancing is paused on your cluster. New Express clusters have it turned on by default, but upgraded clusters do not. With intelligent rebalancing, you can scale your clusters up or down by editing the broker count in your clusters in a single action, and Amazon MSK will keep partitions evenly distributed across brokers. Because MSK provisions one Express broker for each Standard broker, your cluster may have more capacity than your workload needs. Turn on intelligent rebalancing first, then use your post-upgrade metrics to right-size the cluster by reducing the broker count or changing the instance size as required.
Additionally, Express brokers surface an improved bootstrap endpoint for client connections. The boot-XXX.clustername.kafka.us-east-1.amazonaws.com endpoints are managed by MSK Express and improve distribution of connections for metadata requests across your brokers. You can update applications to use these new endpoints at any time to improve reliability and connection distribution. Your applications configured with broker ID-based bootstrap endpoints (for example, b-1.clustername.kafka.us-east-1.amazonaws.com) will continue to function after the upgrade, so this step is optional.
Additional considerations
Beyond these prerequisites, plan for the following during the upgrade window:
- Billing: During the upgrade, MSK adds Express brokers to your existing cluster, matching the size and count of your Standard brokers. For example, for a cluster with 3 kafka.m5.large Standard brokers MSK adds 3 express.m7g.large Express brokers during the upgrade. Because both broker sets are provisioned throughout the upgrade period, you are charged for both broker types until the upgrade completes. There is no additional charge for the upgrade itself.
- Restricted operations: Some cluster modification operations, such as version upgrades, broker configuration changes, and authentication or monitoring changes, are blocked during the upgrade to prevent configuration mismatches between broker types. Kafka read and write, topic create and delete, and broker reboots continue to work. MSK pauses migration during scaling operations and resumes automatically afterward.
- Monitoring metrics: Standard and Express brokers emit different CloudWatch metrics. Plan to update dashboards and alarms as topics move to Express. In particular, replace
KafkaDataLogsDiskUsedwithStorageUsed, and retire Amazon Elastic Block Store (Amazon EBS) storage metrics such asBurstBalance.
Get started with Express brokers on Amazon MSK
The in-place upgrade from Standard brokers to Express brokers gives you a straightforward path to the performance, faster scaling, and lower operational overhead of Express brokers, without application changes, cross-team coordination, or reprocessing state. Amazon MSK handles the broker provisioning, topic movement, and offset preservation for you, whether you let MSK move every topic automatically or move topic by topic. What used to take months of migration effort can now complete in hours.
To move even faster, you can use the managing-amazon-msk skill with your AI coding agent (such as Kiro or any MCP-compatible agent) through the AWS MCP server. The skill assesses your cluster’s compatibility with Express requirements and provides commands to resolve any issues, generates a proof-of-concept package to validate Express performance for your workload, and recommends a right-sized Express cluster footprint.
In-place upgrade to Express brokers is available for MSK Provisioned clusters configured with Standard brokers, in all AWS Regions where MSK Express brokers are supported. To get started, see the Amazon MSK Developer Guide.