Automating identity lifecycle and security with AWS Directory Service APIs

Post Syndicated from Ali Alzand original https://aws.amazon.com/blogs/security/automating-identity-lifecycle-and-security-with-aws-directory-service-apis/

Managing identities and access across complex environments has become more critical than ever. AWS Directory Service for Managed Microsoft Active Directory, also known as AWS Managed Microsoft AD, has added new capabilities to manage users and groups. Now, you can perform create, read, update, and delete (CRUD) operations on users and groups directly through AWS Command Line Interface (AWS CLI), APIs, and the AWS Management Console. You can use this powerful capability to automate identity lifecycle management and enhance security in your AWS environment. By using these APIs, collectively known as the Directory Service Data APIs, you can perform operations such as:

  • Listing users and groups
  • Retrieving user and group details
  • Disabling and enabling user accounts
  • Resetting user passwords
  • Managing group memberships

These APIs provide new possibilities for automating identity management tasks and integrating Active Directory management into your existing workflows and applications.

The introduction of these APIs brings several key benefits:

  • Automation of the identity lifecycle: You can now programmatically manage user accounts throughout their lifecycle—from creation to deletion—enabling streamlined onboarding and offboarding processes.
  • Enhanced security: By integrating these APIs with security services like Amazon GuardDuty, you can create automated responses to potential security threats, such as disabling accounts with inappropriate access.
  • Improved compliance: You can use automated user management to help enforce consistent policies and help maintain compliance with various regulatory requirements.
  • Operational efficiency: You can automate routine tasks such as user provisioning, deprovisioning, and group management, reducing manual effort and the potential for human error.
  • Integration capabilities: By using these APIs, you can seamlessly integrate with existing identity management systems, custom applications, and third-party tools.
  • Cost optimization: By automating processes and reducing manual intervention, you can potentially help your organization optimize operational costs associated with identity management.

In this post, we explore these new APIs and demonstrate how you can use them to create an automated solution for detecting and responding to unexpected behavior by Active Directory users. We walk through a practical example that combines GuardDuty, AWS Step Functions, Amazon EventBridge, and the new AWS Directory Service APIs to create a robust security automation workflow.

Solution overview

To demonstrate the power of these new APIs, let’s explore a practical solution that automates the detection and response to unexpected behavior by Active Directory users. This solution combines several AWS services to create a robust security automation workflow:

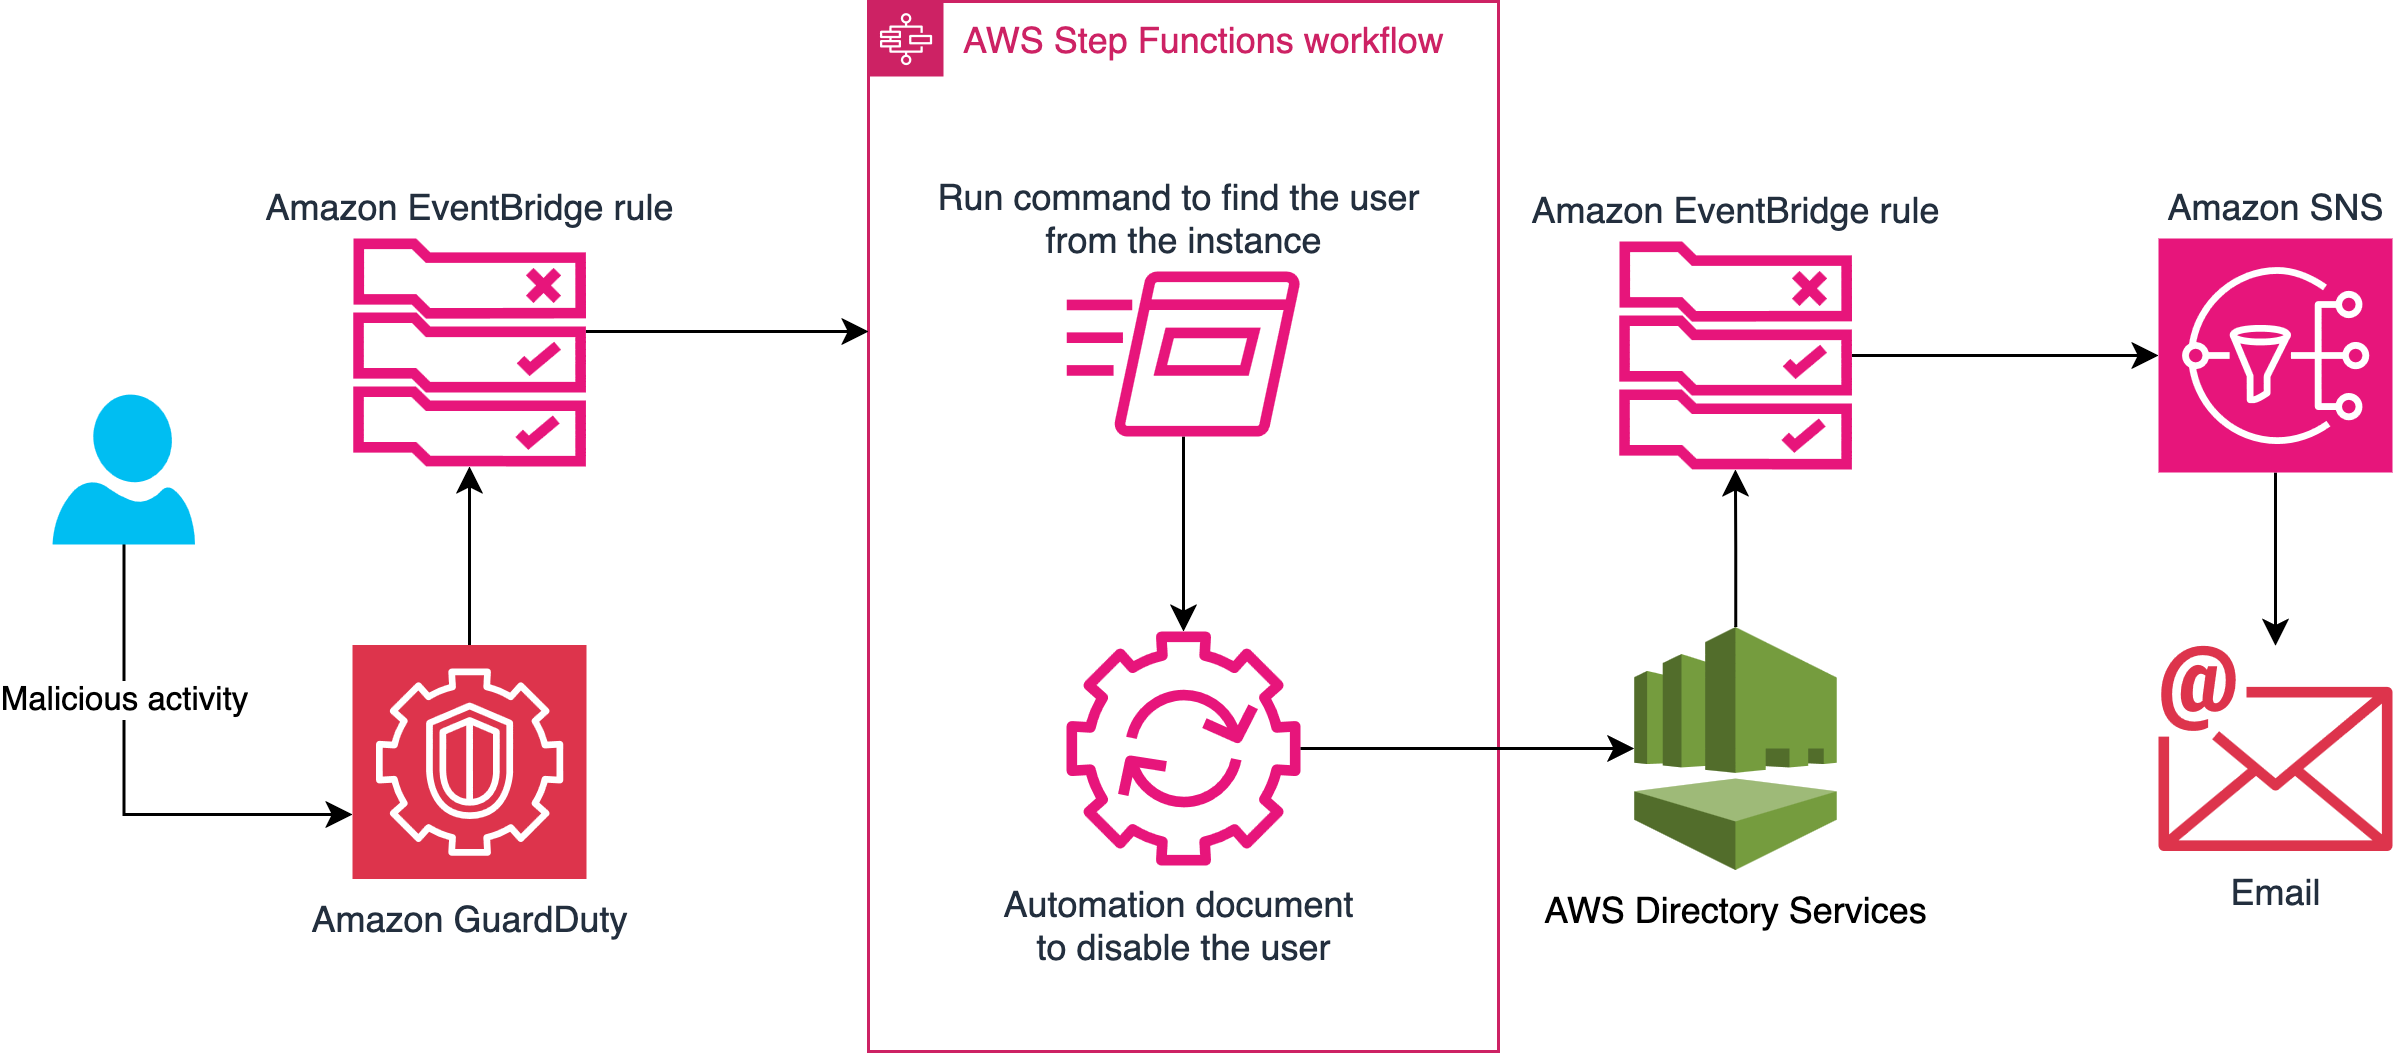
    1. GuardDuty continuously monitors for unexplained behavior of Active Directory users from AWS Managed Microsoft AD. For the example in this post, we’re using Backdoor:Runtime/C&CActivity.B!DNS
    2. An EventBridge rule detects GuardDuty findings related to these users and triggers a Step Functions workflow.
      {
        "detail-type": ["GuardDuty Finding"],
        "source": ["aws.guardduty"],
        "detail": {
          "type": ["Backdoor:Runtime/C&CActivity.B!DNS"]
        }
      }

    3. The Step Functions workflow will:
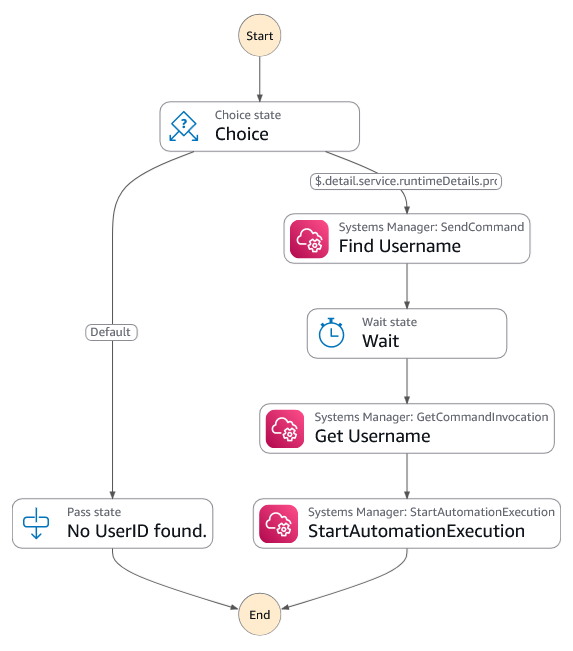
      1. Extract the Active Directory username from the instance using a run command.
      2. Start an automation that will disable the account using the DisableUser API.
Figure 1: Diagram of the Step Functions workflow showing the process of Systems Manager finding the username and starting the automation to disable the account

Figure 1: Diagram of the Step Functions workflow showing the process of Systems Manager finding the username and starting the automation to disable the account

  1. Finally, another EventBridge rule will monitor the DisableUser API call. It will send an email to the user using Amazon Simple Notification Service (Amazon SNS) notifications.
    {
      "detail-type": ["AWS API Call via CloudTrail"],
      "source": ["aws.ds"],
      "detail": {
        "eventSource": ["ds.amazonaws.com"],
        "eventName": ["DisableUser"]
      }
    }

This solution delivers automated, near real-time remediation of potential security threats — significantly reducing exposure windows and containing the impact of unauthorized account access.

The following figure shows a high-level architecture diagram of the solution.

Figure 2: Diagram showing the workflow of what happens when potentially damaging activity is detected

Figure 2: Diagram showing the workflow of what happens when potentially damaging activity is detected

Note: The solution must be deployed in the primary AWS Region of your directory.

Prerequisites

To complete the walkthrough in this post, you must have the following prerequisites in place.

GuardDuty

GuardDuty is an automated threat detection service that continuously monitors for unexpected activity and unauthorized behavior to protect your AWS accounts, workloads, and data stored in Amazon Simple Storage Service (Amazon S3).

To activate GuardDuty:

  1. Go to the GuardDuty console.
    1. If you’re activating GuardDuty for the first time, under Try threat detection with GuardDuty, select All Features and then choose Get Started.
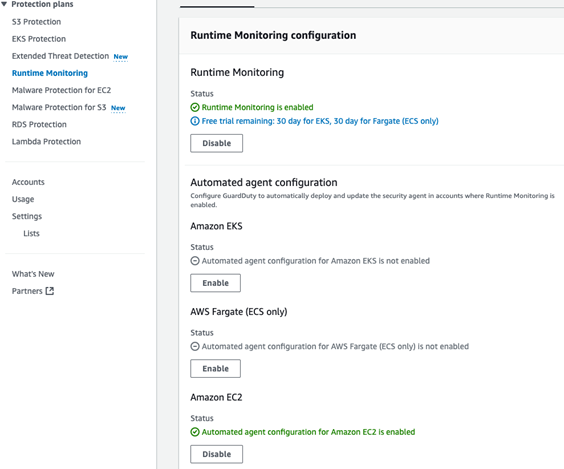
    2. If you’ve used GuardDuty before, select Runtime Monitoring and then choose Enable under Runtime Monitoring.
Figure 3: Runtime Monitoring enabled

Figure 3: Runtime Monitoring enabled

AWS Managed Microsoft AD

AWS Managed Microsoft AD provides a fully managed service for Microsoft Active Directory (AD) in the AWS Cloud. When you create your directory, AWS deploys two domain controllers that are exclusively yours in separate Availability Zones for high availability. For use cases that require even higher resilience and performance in a specific AWS Region or during specific hours, you can scale AWS Managed Microsoft AD by deploying additional domain controllers to meet your needs. These domain controllers can help load balance, increase overall performance, or provide additional nodes to protect against temporary availability issues. Using AWS Managed Microsoft AD, you can define the correct number of domain controllers for your directory based on your use case.

To deploy a new AWS Managed Microsoft AD:

  1. Go to the Directory Service console.
  2. Choose Set up directory and select AWS Managed Microsoft AD.
  3. Select Standard Edition and enter a directory DNS name and password.
  4. Select a virtual private cloud (VPC). For this example, use the Default VPC.
  5. Choose Create directory.

Create a test Active Directory user

You will use this test user account to sign in to an EC2 instance and initiate a command that simulates unexplained activity that results in this account being disabled.

To create the test user, you can use AWS CloudShell or the AWS CLI from your local machine. Run the following commands, replacing the --directory-id value with your own:

# Create the test user
aws ds-data create-user \
 --directory-id "your-directory-id" \
 --sam-account-name "TestUser" \
 --given-name "Test" \
 --surname "User"

Then

# Set a password for the test user 
aws ds reset-user-password \
 --directory-id "your-directory-id" \
 --user-name "TestUser" \
 --new-password "YourSecurePassword123!"

In this example, the password is set to YourSecurePassword123!. If you need to replace it with a password that meets your organization’s requirements, see Resetting and enabling an AWS Managed Microsoft AD user’s password. For more information on creating users, see Creating an AWS Managed Microsoft AD user in the AWS Directory Service documentation.

Test EC2 instance

To generate alerts on GuardDuty, you need a domain joined Linux EC2 instance. If you don’t have a domain joined EC2 Linux instance, follow these instructions for joining a Linux instance to an Active Directory domain. This instance will be used to simulate suspicious activity that triggers a GuardDuty finding and initiates the automated remediation workflow.

Implement the solution

Let’s walk through the steps to implement this solution in your AWS environment.

Deploy the solution

  1. Download the CloudFormation template
  2. Navigate to the CloudFormation console in the AWS account.
  3. For Create Stack, choose with new resources (standard).
  4. For Template source, choose Upload a template file. Choose Choose file and select the template you downloaded in step 1.
  5. Choose Next.
  6. For Stack name, enter a stack name (such as CRUD-API-MAD).
  7. In the Parameters area, do the following:
    1. For DirectoryID, enter the AWS Active Directory ID.
    2. For NotificationEmail, enter the email address to send the notification to.
  8. On the Configure stack options page, choose Next.
  9. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names, then choose Submit.

After the page is refreshed, the status of your stack should be CREATE_IN_PROGRESS. When the status changes to CREATE_COMPLETE, proceed to the next section.

Test

To simulate a threat, use a GuardDuty test domain that GuardDuty will recognize as a command and control server.

  1. Go to the Amazon EC2 console.
  2. Choose Instances from the navigation pane.
  3. Select the test EC2 instance that you created earlier.
  4. Choose Connect, select the Session Manager tab, and choose Connect.
  5. Authenticate with your test user by entering su followed by the test user with the domain name that you created earlier. For example su [email protected], then enter the password.
  6. Enter the command curl guarddutyc2activityb.com.
    You will receive an error because the page won’t resolve, but GuardDuty will have detected concerning events.
  7. Go to the GuardDuty console and select Findings from the navigation pane.
  8. Within 3–5 minutes, you should see a high severity finding for Backdoor:Runtime/C&CActivity.B!DNS.
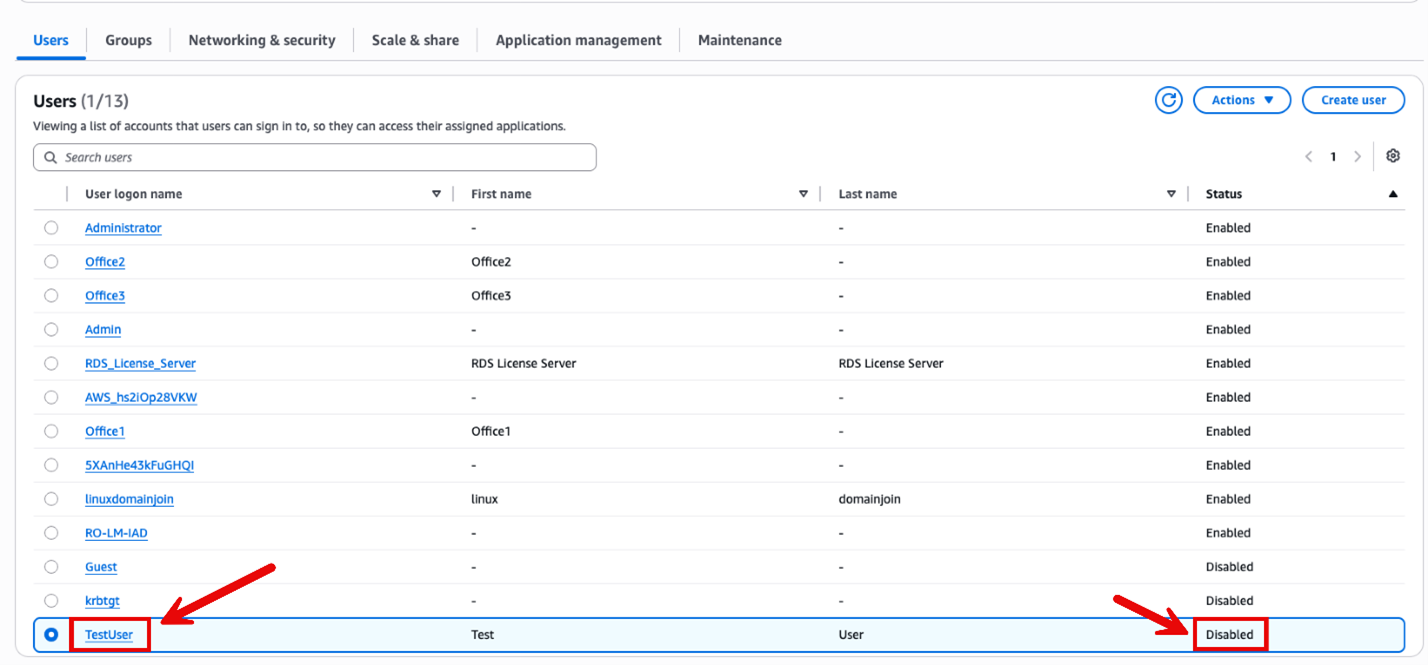
  9. This will then trigger the automation to disable the account.
    Figure 4: Account successfully disabled

    Figure 4: Account successfully disabled

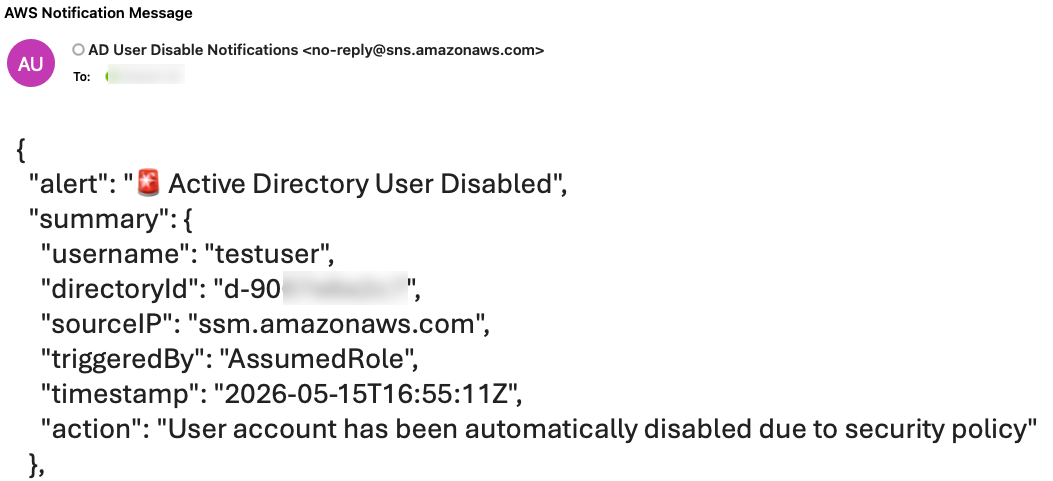
  10. After the account is disabled, an email notification will be sent notifying an administrator that the account was disabled (it might take up to 5 minutes to receive the notification).

    Figure 5: AWS notification message showing the username has been disabled

    Figure 5: AWS notification message showing the username has been disabled

Note: You must archive the GuardDuty finding before running this test again, because the EventBridge rule only runs once against a GuardDuty finding with the same details. To archive the finding, select the check box next to the Backdoor:Runtime/C&CActivity.B!DNS finding, choose Actions (top right), and select Archive.

Conclusion

The new AWS Directory Service APIs for AWS Managed Microsoft AD provide powerful capabilities for programmatically managing Active Directory users and groups. By using these APIs in conjunction with services such as Amazon GuardDuty and AWS Step Functions, you can create sophisticated automation workflows that enhance your security posture and streamline identity management processes.

The solution we’ve explored in this post demonstrates just one of many possible use cases for these new APIs. As you integrate these capabilities into your own environments, you will probably discover numerous opportunities to improve efficiency, security, and compliance in your identity management practices.

For a solution that uses PowerShell Active Directory cmdlets with AWS Systems Manager Run Command to disable users, see How to automatically disable users in AWS Managed Microsoft AD based on GuardDuty findings.

For more information about AWS Directory Service and its APIs, visit the AWS Directory Service documentation.

We’re excited to see how you’ll use these new APIs to innovate and improve your identity management workflows. If you have any questions or want to share your own use cases, leave a comment below or reach out to AWS Support.

Remember, the cloud journey is all about continuous improvement and innovation. Keep exploring, keep learning, and keep pushing the boundaries of what’s possible with AWS.

Ali Alzand

Ali Alzand

Ali is a Senior Infrastructure Migration & Modernization Specialist Solutions Architect at AWS who helps enterprise customers migrate, modernize, and operate their Microsoft workloads on AWS. He specializes in Infrastructure as Code, automating at scale with AWS Systems Manager, EC2 Image Builder, and CloudFormation. He also designs event-driven architectures building responsive, loosely coupled solutions with EventBridge and Lambda. Outside of work, Ali enjoys grilling with friends and discovering new cuisines around town.

Kevin Sookhan

Kevin Sookhan

Kevin is a Specialist Solutions Architect at Amazon Web Services with over 20 years of experience working with Microsoft technologies. He has expertise in running Microsoft workloads on AWS with specialization in helping customers with their migrations, cost optimization, and infrastructure architecture.

[$] BPF support in GCC 16 and beyond

Post Syndicated from daroc original https://lwn.net/Articles/1071973/

José Marchesi and the GCC-BPF developers opened the BPF track at the 2026

Linux Storage,
Filesystem, Memory-management, and BPF Summit

with a 90-minute summary of what has changed for GCC’s BPF support in the past year.
This kind of session has become something of a tradition. There were similar
updates in

2025
and

2024
. This time around, GCC seems to be closing in on
feature parity with the LLVM toolchain — as the slides detail.

OpenBSD 7.9 released

Post Syndicated from corbet original https://lwn.net/Articles/1073933/

The OpenBSD 7.9 release is
out, right on schedule. There is the usual long list of new features,
including improved architecture support, CPU scheduling on heterogeneous
systems, the ability to hibernate a suspended system after a configurable
delay, socket splicing, a
__pledge_open()
system call giving special access to the C library, and much more. See the
announcement and the full
changelog
for details.

НВО: Трагедия в 3 действия

Post Syndicated from original https://www.toest.bg/nvo-tragediya-v-3-deystviya/

Първо действие: Математика

Действащи лица 
В главната роля: Красимир Вълчев, министър на образованието и науката в периода януари 2025 – февруари 2026 г.

Статисти: седмокласници и техните учители и родители

НВО: Трагедия в 3 действия

Учениците, които са седмокласници през настоящата учебна 2025/2026 година, определено не са големи късметлии, що се отнася до учебните им условия. Това е поколението, което завърши още първи клас в онлайн среда (2020 г.). Това е и поколението, което цяла година не знае как точно ще бъде изпитвано и оценявано на предстоящото на 19 юни национално външно оценяване (НВО) по математика. 

Историята започва на 26 август 2025 г., когато министър Красимир Вълчев издава Заповед №РД09-2073. С нея той заповядва на седмокласниците по неведоми пътища да си набавят знания за междупредметните връзки и да се подготвят без учебници и без много-много време за предстоящия изпит. А изпитът никога не е бил провеждан в този формат, нито пък някой учител е виждал в някоя програма, камо ли в учебник гореспоменатите междупредметни връзки.

За математиката, хората и радостта
За красотата на математиката и физиката; за любовта към света и хората; за смисъла в изграждането на общности; за възможността да запалиш пламъка на любопитството у някого. Разговор на Донка Дойчева-Попова и Пейо Попов с гл. ас. Лъчезар Симеонов, който води една необичайна школа по физика.
НВО: Трагедия в 3 действия

Колкото и шантаво да звучи тази история, тя е факт

Министър Красимир Вълчев сложи каруцата пред коня и въведе изпит, за който никой никога не е бил подготвян. Най-тъжното в цялата история беше, че идеята за такъв изпит всъщност изобщо не е лоша. От години в разговорите за реформа на образователната система се прокрадва чудесната (но явно засега твърде авангардна) идея да свържем знанията, придобивани в обучението по отделните предмети, и така да ги направим приложими, близки до реалността и много по-разбираеми за учениците. Уви, досега тези идеи остават на хартия, като добри намерения и изменения в учебните планове и материали няма. 

Двама родители на седмокласници подават жалби срещу заповедта – адв. Снежана Стефанова от Пловдив и Иван Радев от София. Причините: 

Това е грубо нарушение на основни принципи, като правната сигурност, предвидимостта и защитата на легитимните очаквания и представлява превратно упражняване на власт.

Превъртаме напред: след изключително бавен процес (три месеца Върховният административен съд не може да реши кой е компетентният съд за разглеждане на жалбите), едва през февруари 2026 г., в началото на втория учебен срок, заповедта на министъра е отменена от самия него. 

Оценките – (не)нужното зло
Изпитването като опит за унижение и оценката като наказание – това трябва да се промени спешно. Защото колкото и умни реформи да измислим и да приложим, ако има повече човечност, образователната ни система ще се гордее с много по-добри резултати. От Донка Дойчева-Попова.
НВО: Трагедия в 3 действия

Със Заповед №РД09-545/11.02.2026 г. е променено наименованието на изпита, а със Заповед №РД09-546/11.02.2026 г. са променени параметрите на самия изпит.

Красимир Вълчев коментира пред БНТ:

Ще има 24 задачи, които ще бъдат изцяло математически, няма да има задачи с елементи от природните науки, така както е било през предходните години. Нищо друго не променяме във формата, в съдържанието, в продължителността на изпита след седми клас.

И всички заживели щастливо… 

Уви, не.

На 12 февруари тази година Министерството на образованието и науката (МОН) публикува на сайта си Модел на НВО по математика. Само за сравнение: моделът за изпита по български език и литература е публикуван на 12 септември 2025 г. 

Вие след уверение от министъра, че изпитът ще остане в досегашния си формат, бихте ли проверили? Да! Дори е задължително. 

Просто никога не се знае къде е следващият капан 

И този път МОН не разочарова. Без излишни обосновки или доказателства кое точно налага промяна на досегашния формат, той е променен. 

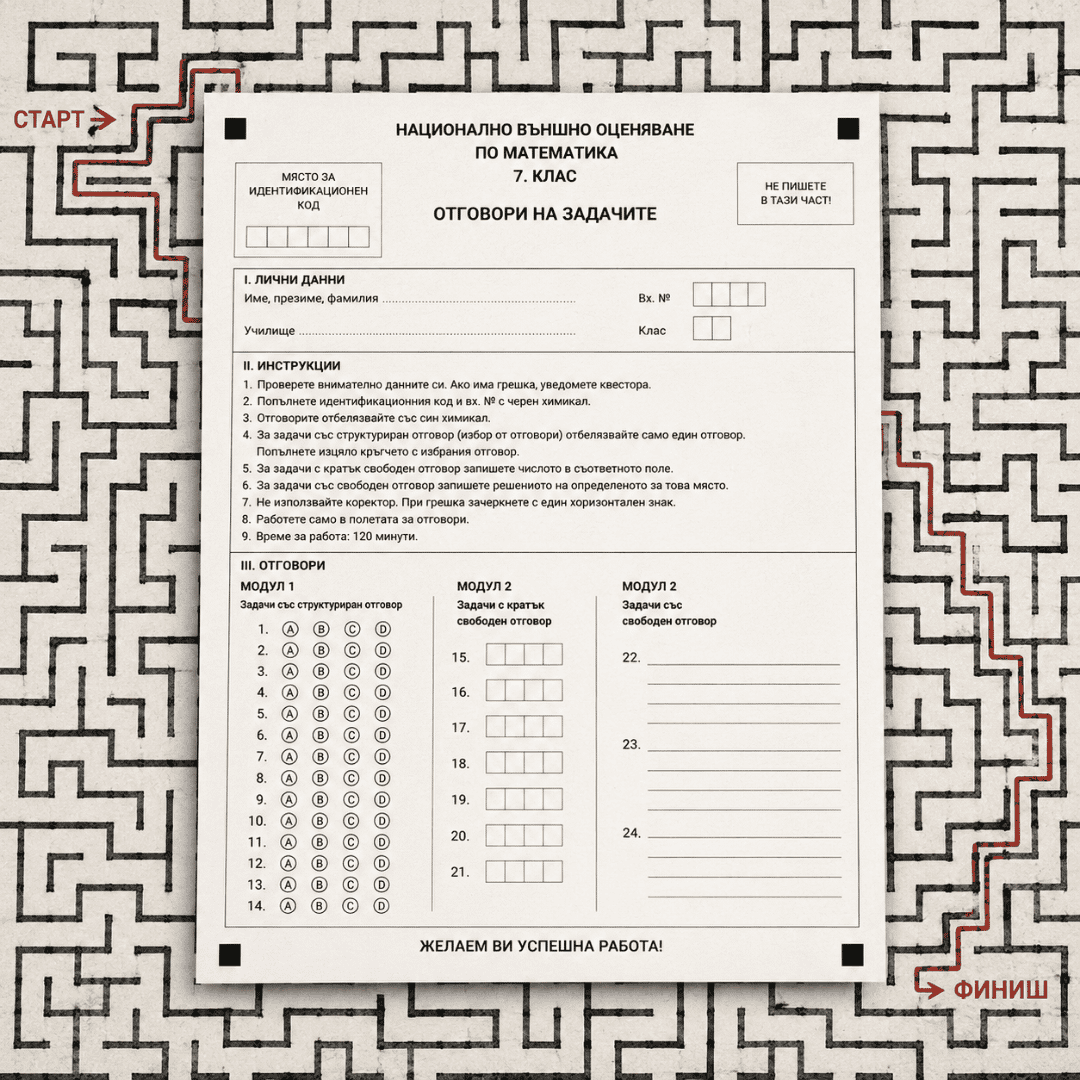
Ето една пътеводна таблица в дебрите на НВО по математика, за да стане по-ясно за какво ще говорим. В нея се вижда от какво точно се е състоял изпитът през последните четири години. 

  • Задачи със структуриран отговор са задачи, чийто отговор може да изберете от 4 предложени възможности. 
  • Задачи с кратък свободен отговор са задачи, чието решение не интересува никого, единственото важно е записаният от изпитвания отговор да е верен.
  • Задачи със свободен отговор са типичните многостъпкови „задачи с думи“, в които става видимо дали учениците могат да правят взаимовръзки и използвайки формули, да стигнат до правилното решение.


Модул 1

Модул 2

2026 г.

14 задачи със структуриран отговор и 7 задачи с кратък свободен отговор (без привеждане на решение)

3 задачи със свободен отговор

2025 г.

20 задачи със структуриран отговор 

3 задачи със свободен отговор

2024 г.

20 задачи със структуриран отговор 

3 задачи със свободен отговор

2023 г.

18 задачи със структуриран отговор и 2 задачи със свободен отговор (без привеждане на решение)

3 задачи със свободен отговор

В тазгодишния изпит са въведени 7 задачи с кратък свободен отговор и в модела на изпита, публикуван на сайта на МОН, има посочени примери. 

Защо тогава преподаватели в VII клас все още не са наясно как точно да подготвят учениците за предстоящия изпит?

В запитване до настоящия министър на образованието проф. д-р Георги Вълчев депутатът от „Демократична България“ Чило Попов изяснява следното:

За последен път при национално външно оценяване по математика в края на 7. клас е имало задачи със свободен отговор през 2023 г., когато те са били под формата на текстова задача без подусловия. Оценяването на тези задачи е било спорно, тъй като всеки ученик е можел да получи на този тип задача или 0 точки, или 4 точки. Това означава, че независимо от използваните знания и приложен подход за решаване на задачата, ученикът е можел или да получи максималния брой точки, или да не получи никакви точки.

Какво казват учителите за този тип задачи?

В групи на учителите по математика в социалните мрежи специалистите дискутират темата и подобни задачи не се одобряват масово. Според преподаватели така не се оценяват адекватно знанията на учениците. Преподаватели, с които разговарях, наблюдават в практиката си често случаи, в които децата решават вярно дадена задача, но предвид възрастта си и стреса по време на изпитване допускат грешка по невнимание – често това са чисто изчислителни грешки. В случая с този тип задачи това би означавало пълна загуба на точките, защото крайният резултат въпреки правилния път на решение е грешен. 

Какво е дискалкулия и защо никой не ѝ обръща внимание?
Дискалкулията е сравнително непознато понятие в България. У нас повече говорим за мързеливи или глупави ученици. Какво е добре да знаем за дискалкулията и защо е толкова важно да говорим за нея без срам и без да се правим, че не я виждаме.
НВО: Трагедия в 3 действия

От друга страна, се допускат и случаи на налучкване и дочуване на правилния резултат, което отново не би показало реалните умения на учениците. В крайна сметка тези задачи се оказват едно ненужно препятствие и не са подходящ инструмент за изпитване.

Но и това не е всичко! 

В публикувания модел въпросните задачи са показани като задачи с две или три подусловия. От МОН са записали със звездичка следното пояснение: 

Наличието на подусловия и броят им ще се определя при съставянето на конкретните изпитни варианти.

Ето така учители и ученици са в неизвестност какво предстои, а първите, които ще видят реалния формат на изпита, са самите изпитвани, при това в деня на изпита.

Остава и един последен, но много важен въпрос: 

как ще бъдат точкувани въпросните седем задачи? 

Остава ли оценяването на пълното им решение с четири точки и отнася ли се то за всички подусловия общо? Дали решението на първото подусловие участва в решението на следващите подусловия? Тук отново може да си представим грешка по невнимание, но правилен подход при всички подусловия и резултатът отново ще е ученик, ощетен от начина на оценяване.

Нека погледнем изпитната ситуация.

Учениците, завършващи VII клас, са на възраст между 13 и 14 години. Тази година освен нововъведените, но неразяснени обстоятелства около задачите има и допълнителна промяна: изпитът ще е с по-голямо времетраене – два модула, всеки от които по 90 минути. Общо три астрономически часа работа! До миналата година по правилник учениците нямаха право да напускат стаята в първите 60 минути от изпита. Това остава ли в сила и тази година? 

Какво казва науката?

Едно от най-разпространените практически правила в областта на психологията на развитието е: „Възрастта по две е равна на концентрацията в минути.“ Това правило не е доказано научно, а по-скоро е емпирично, но отговаря в голяма степен на откритията в тази област. Например резултатите от следното проучване, които доказват:

  •  увеличен брой на грешки по невнимание във възрастта между 12 и 14 години; 
  • краткотрайни пропуски във вниманието: пренебрегване на стимули поради изместване на фокуса;
  • грешките не са в резултат на импулсивност, а се дължат на пропуски в концентрацията.

Фронталният лоб на мозъка на 12–14-годишните все още не е достатъчно развит и те не са достигнали оптималните си нива на концентрация, каквито са типични за възрастните. Биологичните връзки в мозъка са в процес на изграждане. Тоест мозъкът на 13-годишните изглежда като огромен строителен обект в най-активната си фаза. Нищо не е готово, въпреки че вече е добило приблизителните си окончателни размери и краен вид.

Първо действие на тази трагедия не завършва добре. За учениците. За МОН още не е ясно. Но оттам сме свикнали да има сравнения: „Тази година средният успех на НВО-то по математика се понижи.“ В сравнение с какво, при положение че нямаме повече от две години с един и същ изпит?

Въпросът „Какво измерваме?“ трябва непременно да върви ръка за ръка с въпросите „Защо го измерваме?“ и „Как го измерваме?“. 

[$] Support for private memory nodes

Post Syndicated from corbet original https://lwn.net/Articles/1072881/

Gregory Price started his session in the memory-management track of the
2026 Linux Storage,
Filesystem, Memory Management, and BPF Summit
by saying that, in
current kernels, if a NUMA node has memory, the assumption is that anybody can
make use of it. He is trying to implement the opposite policy — to make
some memory off-limits for all processes except those designed specifically
to use it. The session was used to present his goals and to discuss how
they might be implemented.

Security updates for Thursday

Post Syndicated from corbet original https://lwn.net/Articles/1073860/

Security updates have been issued by AlmaLinux (kernel, kernel-rt, and libsndfile), Debian (bind9, evince, firefox-esr, openjpeg2, pdns, and rsync), Fedora (erlang-cowlib, evince, expat, firefox, kernel, mingw-expat, mysql8.0, mysql8.4, nss, opencryptoki, pgadmin4, proftpd, python-django5, python-django6, python-dotenv, rsync, rust-nu, rustup, and strongswan), Oracle (nginx, nginx:1.24, ruby, ruby:3.3, and squid), Slackware (bind and rsync), SUSE (buildah, distribution, distribution-registry, docker, firefox-esr, helm, libpainter0, libsdb2_4_2, postgresql-jdbc, runc, and vim), and Ubuntu (gnutls28, gst-plugins-good1.0, jq, linux-nvidia, linux-nvidia-lowlatency, openvpn, rsync, and unbound).

Q1 2026 Threat Landscape Report: Zero-clicks, geopolitical tensions, and some wins for law enforcement

Post Syndicated from Rapid7 Labs original https://www.rapid7.com/blog/post/tr-q1-2026-threat-landscape-report-geopolitics-ransomware

The first quarter of 2026 reinforced that attackers are moving faster, operating with greater coordination, and exploiting weaknesses before most organizations can respond effectively. From escalating geopolitical tensions to increasingly aggressive ransomware operations, the latest quarterly Threat Landscape Report highlights a security environment where reactive defense strategies are becoming unsustainable.

Quarterly Threat Landscape Report findings

Exploits unseat social engineering for top initial access vector (IAV)

One of the biggest takeaways is that vulnerability exploitation surpassed social engineering as the largest initial access vector with 38% of the total. This would be interesting on its own, but when coupled with more than 50% of all exploited vulnerabilities actively being zero-click, network facing vulnerabilities, it indicates that, at least in the short term, attackers are finding AI-enabled vulnerability exploitation easier to accomplish than exploiting human behavior. These types of vulnerabilities require no authentication and no user interaction, giving attackers rapid pathways into exposed systems and edge infrastructure. At the same time, exploitation activity was frequently preceded by large spikes in public discussion across forums, blogs, and social media platforms, demonstrating how quickly threat actors operationalize publicly available information once vulnerabilities gain visibility.

Geopolitics and FBI takedowns in the threat landscape

Geopolitical instability also continued to shape cyber operations throughout the quarter, particularly in the Middle East, where cyber activity was increasingly synchronized with military escalation. Iranian state-aligned groups targeted government infrastructure, financial services, and industrial systems, while Russian and Chinese campaigns focused heavily on intelligence collection, telecommunications infrastructure, and persistent access operations designed to remain undetected over long periods of time. The result is a threat landscape where organizations must prepare not only for immediate disruption, but also for long-term persistence inside enterprise environments.

Meanwhile, law enforcement operations targeting underground criminal infrastructure disrupted several major ransomware and credential marketplaces during Q1, including the seizure of RAMP and LeakBase. These takedowns have created operational pressure for cybercriminal groups, pushing threat actors toward smaller, decentralized communities and increasing internal distrust.

A marked shift towards “pure extortion”

The report also highlights the continued evolution of ransomware operations, particularly the growing shift toward “pure extortion” tactics focused on rapid data theft rather than traditional encryption-based attacks. Threat actors increasingly leveraged zero-click vulnerabilities to gain initial access, exfiltrate sensitive data, and pressure victims without deploying ransomware payloads that create additional operational risk and visibility.

Taken together, the findings from Q1 2026 show that organizations can no longer rely on periodic assessments and reactive workflows alone. Security teams need continuous visibility into their attack surface, better prioritization around exploitable risk, and the ability to move at a pace that matches modern attackers before small exposures become large-scale incidents.

Download the full report here.

Ограниченията във въздушното пространство на България

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/gdgba/

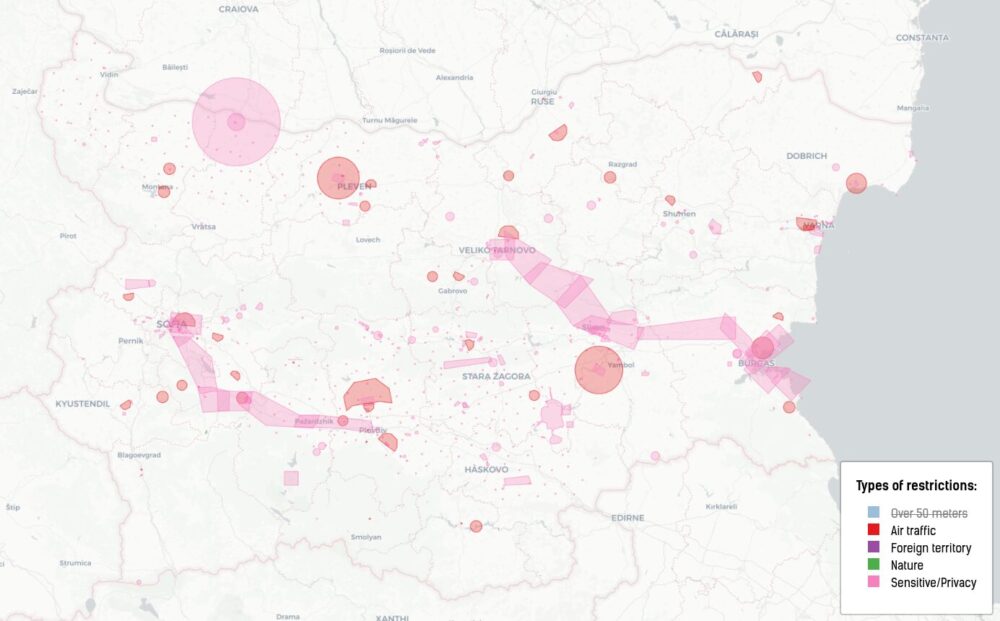
Преди седмица написах статия за това как все още няма ограничителни зони за дронове около площадките за медицински хеликоптери. Макар това да е вероятно най-малкият проблем в това начинание, все пак създава риск. Скоро след това @dhardestbattles.bsky.social ме поправи в Blusky, че всъщност има сериозно разминаване между интерактивната карта на ГД ГВА и JSON файла, който предоставят. Наистина, на страницата им пише, че картата е само индикативна. Моя грешка е да предположа, че няма толкова голяма разлика между двете.

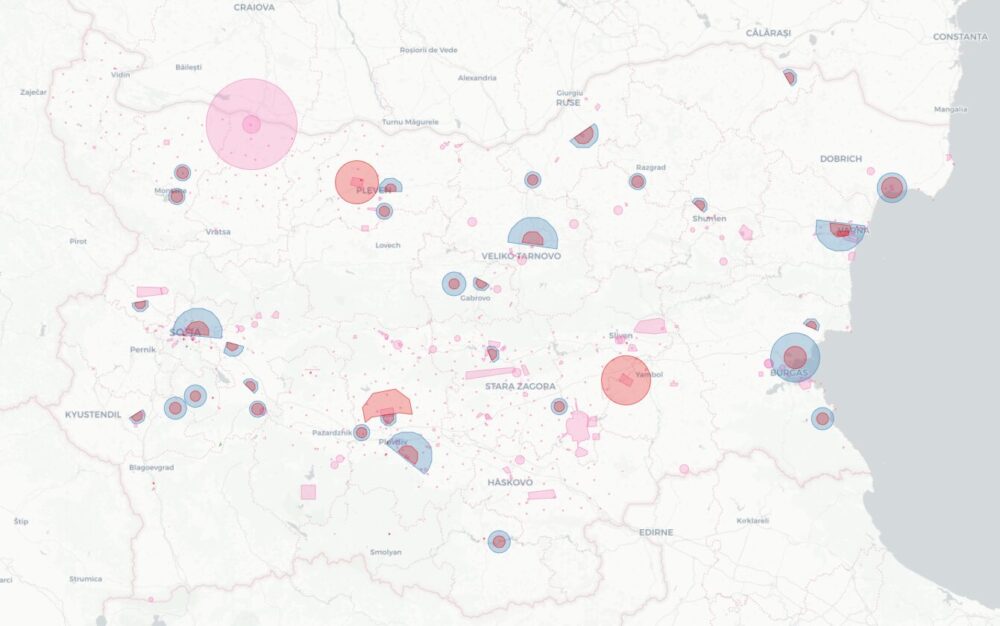
Затова, както правя обикновено, седнах да направя карта, която да показва реалните данни на ограниченията на въздушното пространство. Доколкото има готови професионални инструменти за представяне на специализирания формат, целта ми беше по-скоро да направя карта, която да ни позволи да оценим работата на дирекцията и най-вече исканията за такива ограничения. Картата няма за цел да е отправна точка и всеки следва да сверява с официалната страница на ГД ГВА.

Методология и условности

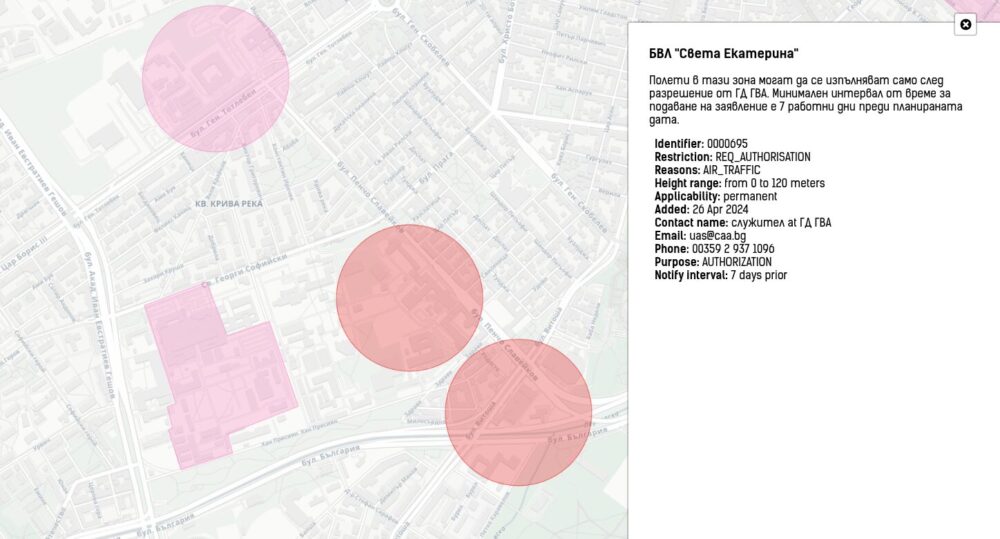
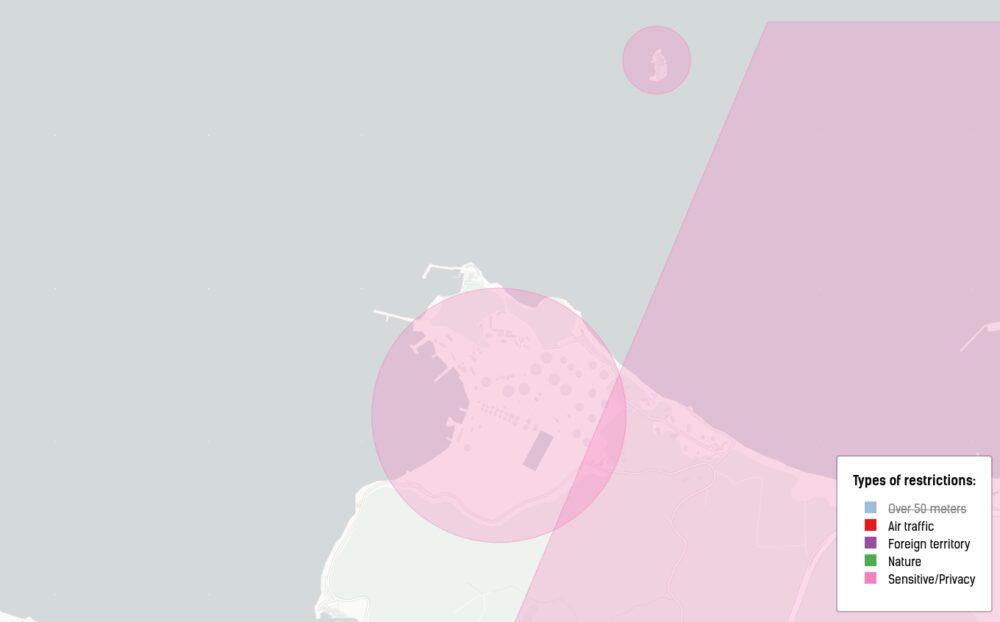
Този път реших да направя картата на английски заради съдържанието на повечето полета във формата. Само текстовото описание на ограничението е на български, което намирам за странно в случая. Добавих филтри по тип ограничение и към тях добавих зоните над 50м. около летищата. Така може да се изключват категории като натиснете на легендата. При натискане където и да е се отваря информация за всички ограничения на това място спрямо филтрите. Така разбираме какво е естеството на ограниченията. Повечето са изискване за уведомяване или искане на разрешение в определен период преди полета. Има лице за контакт и други параметри. С бутоните горе вляво може да сменяте картата на сателитна снимка както и да я фокусирате върху местоположението си.

Направих така, че картата да зарежда всеки ден информацията за ограниченията, ако има нова такава. Докато я правих забелязах, че са обновили файла междувременно – на 15 и 18-ти май. Затова ми хрумна да заредя всички публични промени в последните години. Има 21 такива от май 2023-та насам. Преди това не са публикували JSON файла, а са разчитали на въпросната индикативна карта. Тя обаче няма историческа справка. Затова нямаме данните за зоната, например, около игрището, където Борисов риташе мачле край ресторанта на Сталийски.

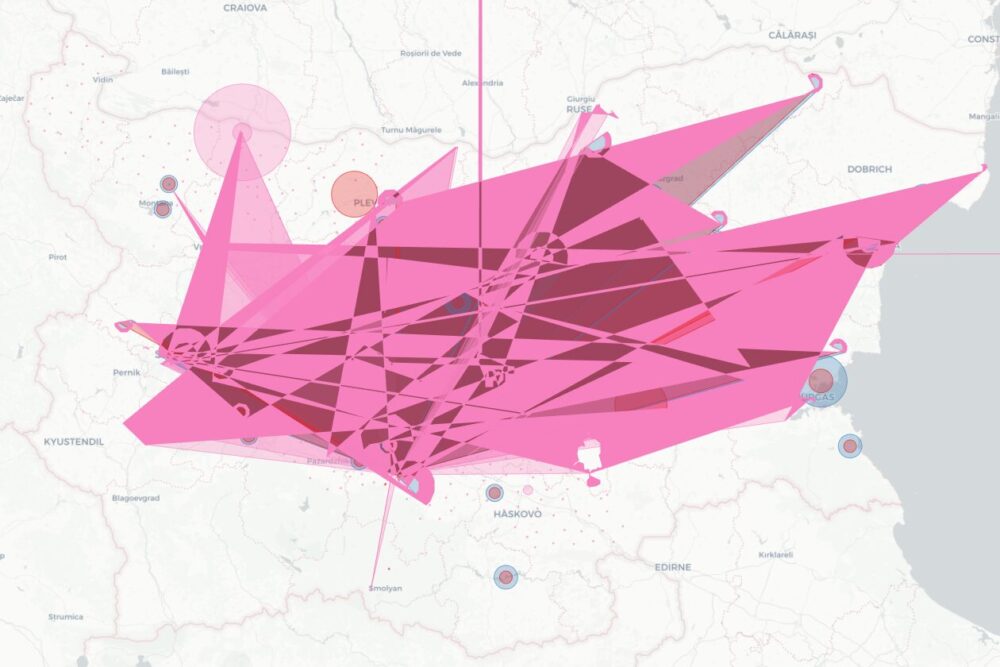
19 от тези архива с ограничения добавих на картата. Може да се покажат с бутона горе вляво за филтър и после да се избере дата от менюто. Архивите от май и юни 2023-та, за съжаление, са неизползваеми. Както виждате долу, при създаването им са объркали географския формат на полигоните. Можех да ги оправя, но тогава ще трябва да правят твърде много предположения и се губи смисълът.

Това, което са добавяли тогава обаче в последствие е въведено все пак във валидни ограничения и ги виждаме в следващите архиви. Някои от зоните са изтривани и въвеждани наново. Ако натиснете на някоя от тях ще видите кога са първо въведени и кога са изтрити. Някои от тях обаче е да са въведени наново на по-късен етап и на същото място да е имало друга зона дори със същия идентификатор, макар с различни параметри. На доста от зоните пиша, че са въведени най-късно през 2023-та, тъй като нямам по-стари данни.

Хеликоптерните площадки

Както споменах в предишната си статия, към този момент има 20 площадки за медицински хеликоптери в болници из цяла България. На интерактивната карта на ГД ГВА няма ограничения за дронове на никоя от тях. В официалния JSON файл обаче има за 12 от тях. Тези без ограничения са:

  • УМБАЛ „Проф. д-р Стоян Киркович“ в Стара Загора
  • МБАЛ „Д-р Тота Венкова“ и МБАЛ „Свети Иван Рилски“ в Габрово
  • МБАЛ „Света Петка“ във Видин
  • МБАЛ „Д-р Иван Селимински“ в Сливен
  • МБАЛ „Сърце и Мозък“ в Плевен
  • МБАЛ „Д-р Братан Шукеров“ АД в Смолян
  • МБАЛ „Хасково“
Ограниченията около Св. Екатерина в София, която използвах за илюстрация в предишните ми статии

Всички тези са добавени в списъка на дирекцията след средата на 2025-та. Повечето от ограниченията за останалите 12 са добавени през 2024-та и преди запитването ми до ГД ГВА през 2025-та защо не се виждат такива на картата. Интересното тук е, че тогава те не ми отговориха, че всъщност има ограничения и картата е само индикативна. Вместо това ми отговориха, че все още се работи по процеса и всъщност не било задължително да има ограничения за дронове.

Особености на ограниченията

Моята интерактивна карта може да разгледате тук или на нов екран.

По нея може да направим няколко интересни наблюдения. В Тракия между Сливен и София, както и в северозападна България на запад от Плевен се виждат множество ограничителни зони свързани с площадки за борба с градушките. Друг пример са ограниченията около Росенец обхващащи почти целия полуостров, но без резиденцията на Доган.

Като друг пример виждате ограничения въведени между 8-ми и 15-ти май от земята до 305 метра за дронове по пътя между Бургас и Велико Търново и Пловдив и София. Това изглежда са ограничения свързани с провеждането на Giro d’Italia по това време. Тогава имаше доста хеликоптери отразяващи събитието и явно целта е била да се пазят те от дронове на зрителите.

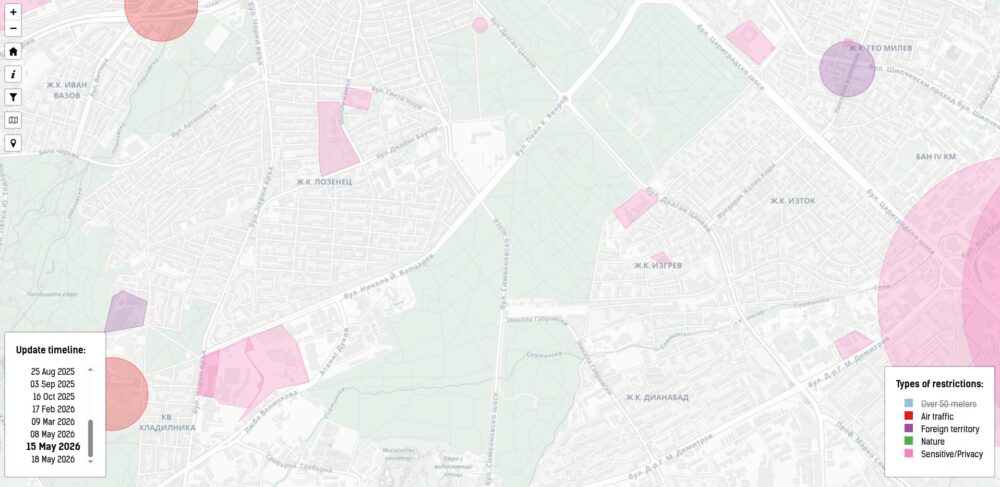
По същото време се забелязва и добавено ограничение в Лозенец и Изгрев. Те съвпадат с Руското посолство, Руското търговско представителство и Руското училище в Лозенец и са в категория чувствителни обекти. Махнати са на на 18-ти май и не откривам публична информация защо. На същата карта виждате ограниченията около посолствата на Израел и САЩ в категория „чужда територия“. Такива обаче няма около руското, немското и другите посолства в района. Виждаме ограничения за „чувствителни обекти“ около комплекса на НСС и МВнР

Виждаме също ограничение ERM2 в Лозенец на границата на Борисовата градина. Там се намира намира подстанция Рила. Стана известна след спирането на тока в целия център на София по време на масовите протести през декември 2025-та. Тогава имаше обосновани предположения за умишлен саботаж. Интересно е, че ограниченията за дронове на това място до 120 м. е въведено четири месеца по-рано – през август.

На картата може да се видят още доста такива зони. Повечето са свързани с летища, военни или други държавни обекти. Има няколко в категория природни обекти, макар да се броят на пръсти. Един такъв е целият язовир Бели Искър. По някаква причина са добавили пречиствателните станции Бистрица, Панчерево и Кубратово в тази категория. Изглежда категорията не се отнася до опазване на защитени природни зони от шум, а на инфраструктура.

Какво друго интересно забелязвате в данните?

AMD Details Ryzen AI Halo AI Dev Mini-PC, Pre-Orders In June For $3999

Post Syndicated from Ryan Smith original https://www.servethehome.com/amd-details-ryzen-ai-halo-ai-dev-mini-pc-pre-orders-in-june-for-3999/

Ahead of June pre-orders, AMD is releasing more information about their forthcoming AI dev box, the Ryzen AI Halo. The AI mini-PC will come pre-loaded with a comprehensive AMD software stack and carry a $3999 price tag

The post AMD Details Ryzen AI Halo AI Dev Mini-PC, Pre-Orders In June For $3999 appeared first on ServeTheHome.

AMD Ups Ante With 192GB Ryzen AI Max PRO 400 Chips for AI Systems

Post Syndicated from Ryan Smith original https://www.servethehome.com/amd-reveals-ryzen-ai-max-pro-400-series-192gb-ram-for-ai-systems/

AMD is adding a trio of new chips to its Ryzen AI Max portfolio. The 400 series chips will bring support for up to 192GB of memory to AI systems, allowing for larger local models than ever before

The post AMD Ups Ante With 192GB Ryzen AI Max PRO 400 Chips for AI Systems appeared first on ServeTheHome.

Why Policy in Amazon Bedrock AgentCore chose Cedar for securing agentic workflows

Post Syndicated from Liana Hadarean original https://aws.amazon.com/blogs/security/why-policy-in-amazon-bedrock-agentcore-chose-cedar-for-securing-agentic-workflows/

Agents have agency: they adapt and find multiple ways to solve problems. This autonomy creates a fundamental security challenge: the large language model (LLM) at the heart of the agent is non-deterministic, and its decisions can’t be predicted or guaranteed in advance. It can hallucinate harmful actions with complete confidence. It’s vulnerable to prompt injection attacks, where adversaries inject malicious commands through tool responses or user inputs. LLMs don’t robustly differentiate between commands and data, everything is only tokens. For these reasons, if you want defense in depth, you must treat the LLM as an untrusted actor from a security point of view.

The insight is that the LLM can’t affect the external world directly: it has to go through an orchestrator that invokes tools based on the LLM’s output. This is precisely where the controls must be applied. What you need at this boundary is authorization: a decision about whether each tool invocation should be allowed and under what conditions. Consider a customer service agent for an online retailer. Without proper controls, it could process refunds that exceed authorized limits, apply discounts to product categories that should be excluded, or look up one customer’s data while handling another customer’s session.

If you control agents’ access to tools, you can establish a safety envelope within which the agent can operate freely. This differs from two common but unsatisfactory approaches:

  • Creating hard-coded workflows eliminates uncertainty, but by itself defeats the purpose of using an LLM as the brain of the agent, because you’ve built a traditional application with an LLM interface. And even with this restriction, using LLM outputs at any step can open up the same risks. While it’s a useful technique for well-understood workflows, it’s not sufficient for agents that need to adapt.
  • Human-in-the-loop provides a safety net for critical operations, and it will always have a role. But relying on it as the main control mechanism sacrifices autonomy and can lead to approval fatigue.

You need agents that are safe and autonomous. This requires an auditable, deterministic enforcement layer that sits outside the agent and tools. Why outside? Because the LLM’s plan is the thing you can’t trust—it can’t be responsible for enforcing its own constraints. Controls at the LLM layer—such as system prompts and training-time alignment—can be bypassed by prompt injection or hallucination. Hard-coded checks in agent or tool code are more robust, but become difficult to audit and manage at scale, especially when security logic is scattered across many tools and services. Centralizing authorization outside both gives you a single checkpoint the LLM can’t circumvent; one that’s auditable and can be verified independently of the application code.

This is where AgentCore Policies come in. Amazon Bedrock AgentCore Gateway sits between the agent and the remote tools it calls. When you associate a Policy with a Gateway, it blocks everything by default. Policies selectively open this boundary by specifying which tool invocations are allowed and under what conditions. This enforcement applies to all tool traffic routed through the Gateway. For this approach to scale, it must be more straightforward to reason about the policies than about the agent’s behavior.

AgentCore policies are expressed in Cedar. Cedar is an open source authorization policy language developed by AWS that has recently joined the Cloud Native Computing Foundation (CNCF). Cedar was designed with exactly these properties: it’s purpose-built for authorization, readable by humans, and analyzable by machines using automated reasoning. This gives enterprises the ability to scale policy definition and enforcement to their AI agents.

How Cedar is used by Amazon Bedrock AgentCore

Amazon Bedrock AgentCore provides the infrastructure to deploy and manage agents at scale. It includes AgentCore Runtime for hosting agents, AgentCore Gateway for managing how agents connect to tools using Model Context Protocol (MCP), and Policy in AgentCore. Policy intercepts all agent traffic through AgentCore gateways and evaluates each request against defined policies in the policy engine before allowing tool access. Cedar powers the policy layer.

AgentCore Policy uses Cedar and its mathematical analysis capabilities at several points in the AgentCore Gateway workflow: the Cedar authorization engine is used at policy evaluation and Cedar Analysis is used during policy authoring, and in the control plane.

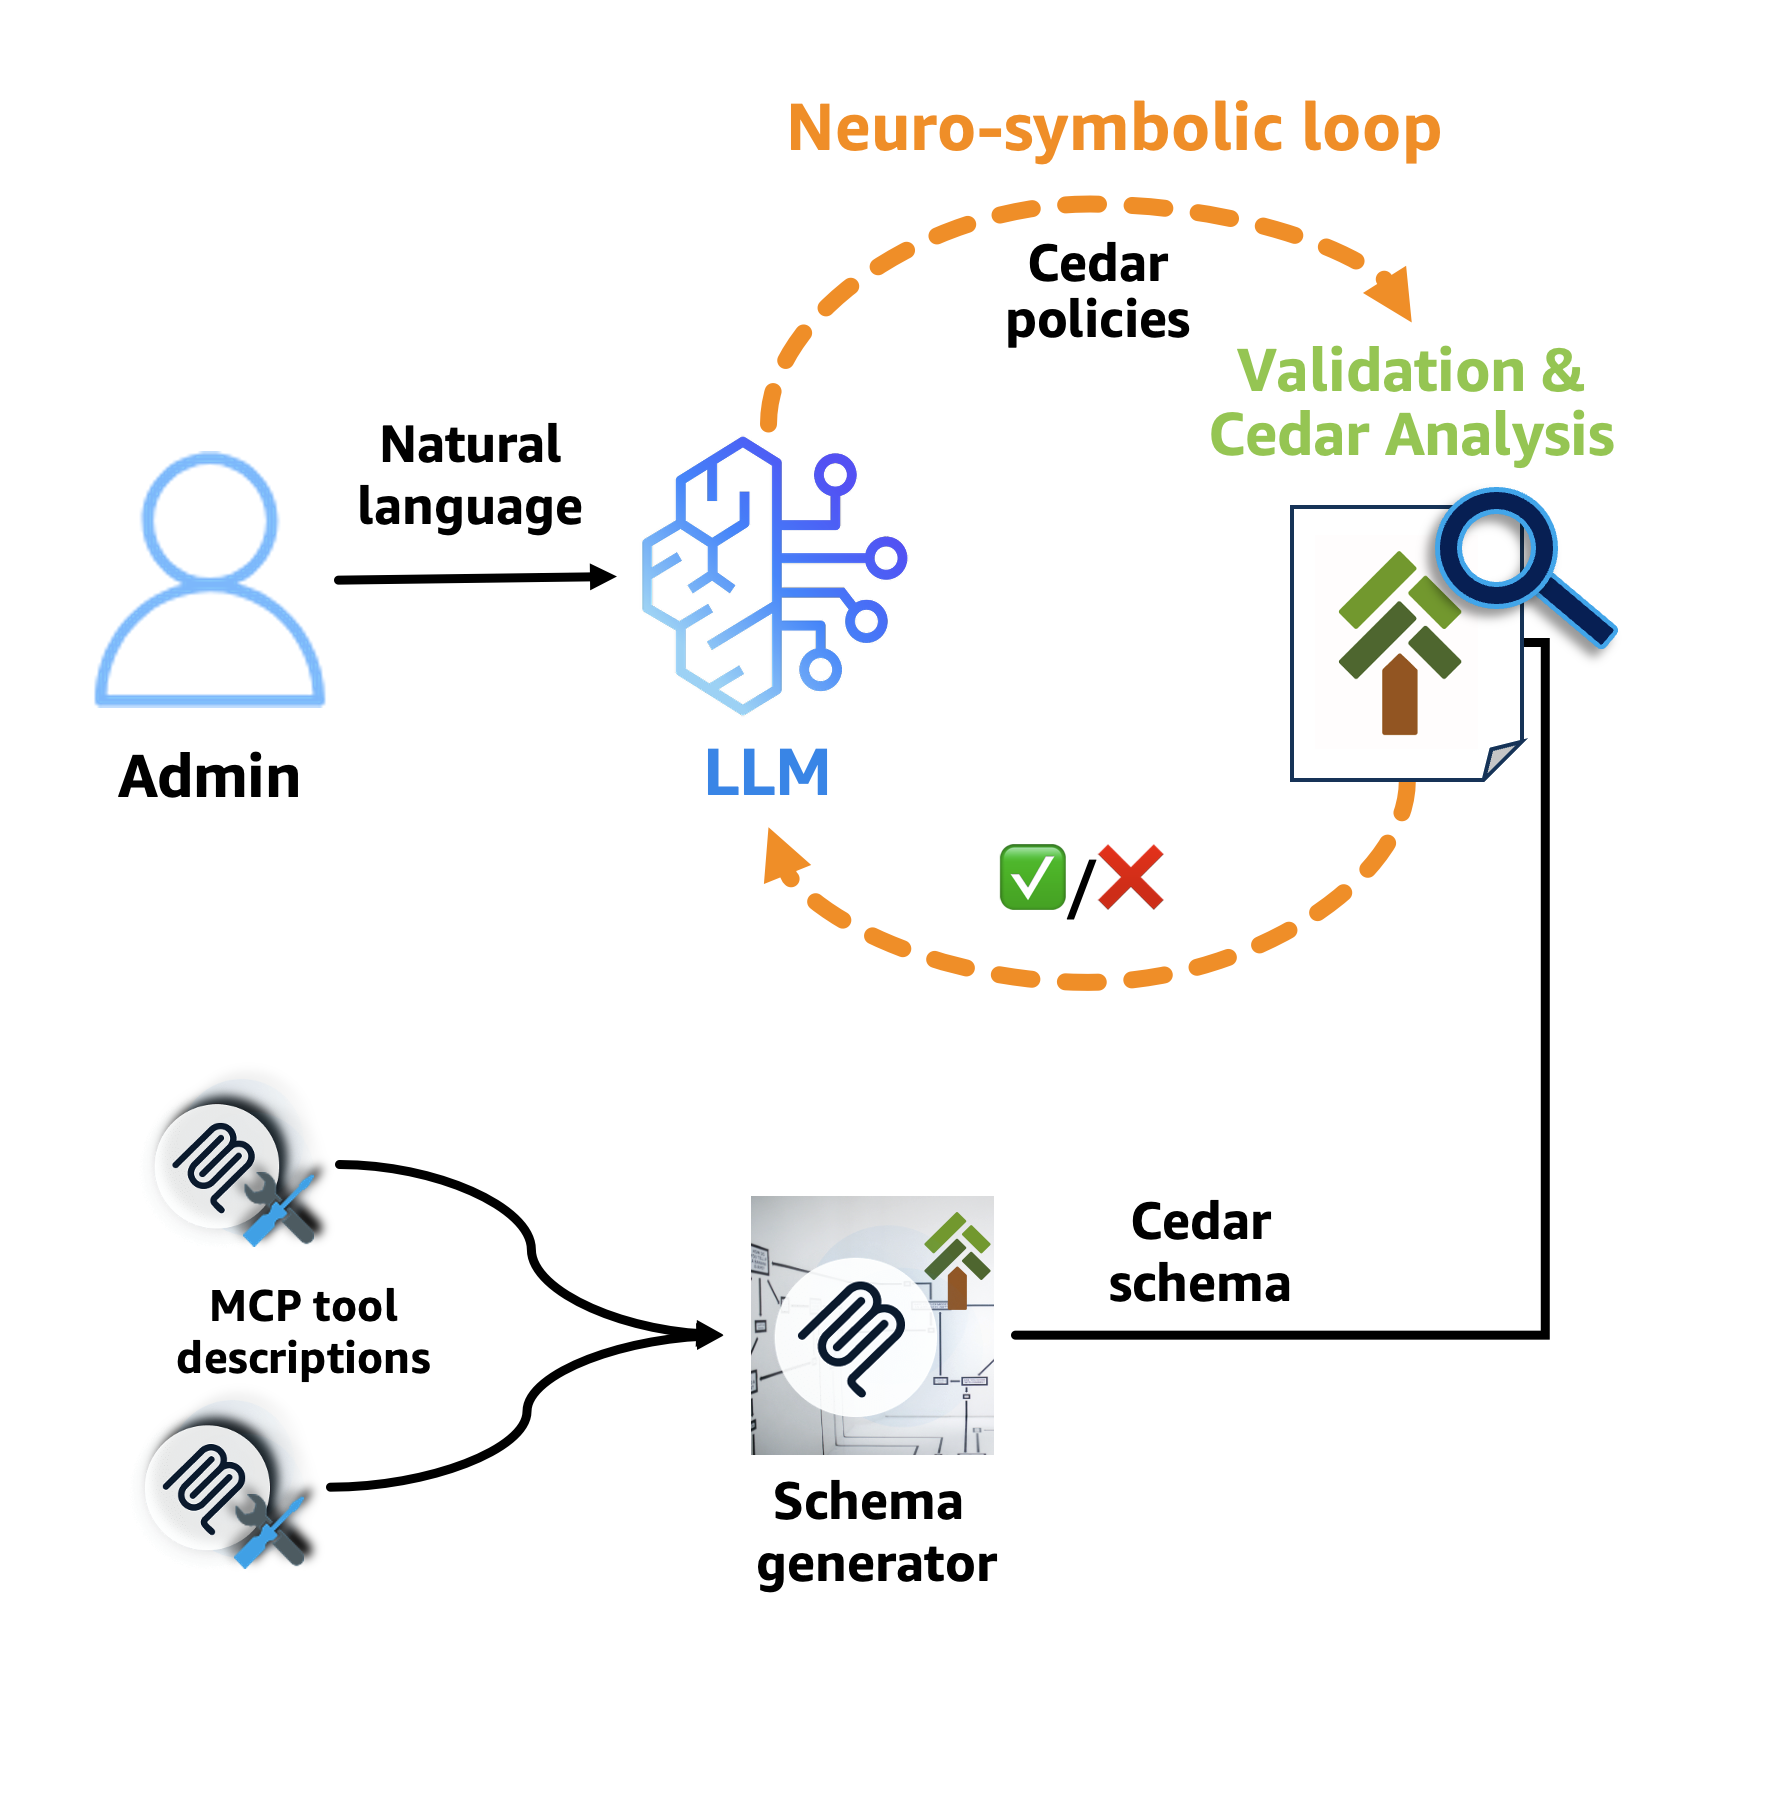
Policy authoring: Developers can write Cedar policies directly or use natural language that gets translated to Cedar through a neuro-symbolic AI feedback loop. Neuro-symbolic AI combines machine learning’s flexibility with automated reasoning’s provable correctness. An LLM generates policies from natural language, while Cedar Analysis validates them using symbolic, mathematical reasoning. The following diagram illustrates this workflow:

Figure 1: Cedar policy generation workflow

Figure 1: Cedar policy generation workflow

An administrator specifies—in natural language—which MCP tools the agent can call and under what conditions. The neuro-symbolic feedback loop then formalizes this description into Cedar policies. Here’s how it works: first, the LLM translates the natural language into Cedar policies. These policies are then run through two stages of verification. In the first stage, AgentCore Policy uses a Cedar schema generator that takes the MCP tool descriptions and produces a Cedar schema. Cedar validates the policies against this schema, helping to ensure that they reference valid tools and parameters and ruling out whole classes of runtime errors. If validation passes, the second stage runs Cedar Analysis, which encodes each policy as a mathematical formula and detects issues like policies that grant or deny everything, or that contain impossible conditions. These mathematical proofs identify errors in the process of translating from the natural language description to Cedar policies, and guide corrections.

The neuro-symbolic feedback loop significantly improves the accuracy of the generated policies. This demonstrates the power of combining neural and symbolic approaches—the LLM provides creative translation from natural language, while automated reasoning provides rigorous validation.

Control plane: When attaching policies to an AgentCore Gateway, Cedar Analysis performs holistic analysis of the entire policy set. Instead of analyzing policies in isolation, it examines how they interact and their combined effect. This analysis identifies potential logical errors—such as conflicting or redundant policies—and detects whether the policy set produces unintended authorization outcomes. When Cedar Analysis detects these errors, the operation fails and returns a description of the issue, so the policy author can fix and retry. See the Formal analysis for policy verification section for examples of the checks.

MCP tool invocation enforcement: Each agent tool request made to the AgentCore gateway is evaluated against Cedar policies which determine whether the MCP tool invocation with the given arguments should be allowed. This creates the safety envelope while allowing the necessary bridges to enable the agent to perform its job.

MCP tool filtering: Cedar enables an additional layer of protection that operates before any tool invocation occurs. When an agent issues a list tools command, AgentCore Gateway uses Cedar’s partial evaluation capability to determine which actions would always be denied under the current policy set. Those actions are omitted from the list tool response. The agent and the underlying LLM never see those tool actions, eliminating an entire class of risk: the agent and LLM can’t attempt to invoke a tool it doesn’t know exists. This is a direct benefit of Cedar’s partial evaluation: the system can determine that certain tool actions are unreachable without needing to wait for an actual tool invocation attempt.

Why Cedar: Analyzability enables safety at scale

Natural language is too ambiguous for security-critical infrastructure, and general-purpose programming languages, like Python, are very expressive but too difficult to analyze. They can have unintended side effects, termination issues, and can be difficult to understand.

Cedar avoids these issues by excluding loops and stateful operations, so policy evaluation terminates in O(n) time in common cases. This bounded execution time means agents can make authorization decisions without disrupting user experience or workflow efficiency.

Cedar is straightforward to read. Regulatory compliance and security audits require policies that humans can understand and verify. Cedar policies read like structured natural language, making them accessible to security teams, compliance officers, and business stakeholders:

// Only allow bulk discounts for premium customers with sufficient quantity
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Platinum" &&
  context.input.orderQuantity >= 50
}
unless
{
  context.input
    .productTypes
    .containsAny
    (
      ["limited_edition", "seasonal_specials"]
    )
};

Auditors without a technical background can understand this policy: “Allow bulk discounts for platinum customers who order at least 50 items, except for limited edition or seasonal special products.” The unless clause makes the exception clear, which is how business rules are typically expressed in natural language. Notice that this single policy constrains two different sources of data. The customer tier comes from a JSON Web Token (JWT) claim—it can’t be hallucinated or manipulated by the LLM. The tool inputs like order quantity and product types, however, originate from the LLM’s tool call. Cedar policies constrain these inputs to only allowed values, ensuring that even if the LLM produces unexpected arguments, the policy enforcement layer rejects them deterministically.

Cedar is the right choice because it’s fast, straightforward to read, and analyzable through automated reasoning. This analyzability is why you can reason about the safety envelope around agents that’s expressed as Cedar policies. As agentic systems grow the number of tools grows. Without proper tooling, policy management becomes intractable; policies can conflict, create security gaps, or produce unintended authorization outcomes.

In the rest of this section, we examine how Cedar’s analyzability directly addresses this challenge through its deterministic, mathematically sound analysis. Because Cedar analysis can reliably detect conflicts and logical errors across large policy sets it enables scalable policy management through neuro-symbolic AI.

Formal analysis for policy verification

Cedar policies can be encoded as mathematical formulas and analyzed using automated reasoning techniques through a symbolic encoder. This enables AgentCore Policy to provide sophisticated policy verification capabilities during policy authoring and beyond. AgentCore Policy uses this analysis when authoring or attaching policies to detect possible logical errors, such as conflicting or redundant policies. Policy analysis, including policy comparison is available as an open source CLI tool. Next, we will take a look at some concrete examples of these checks.

Detecting logical errors in policies: Cedar Analysis can detect when policies contain logical errors. For example, the following policy has contradictory constraints that mean it can’t allow any request: the customer tier can’t be both gold and platinum at the same time. The intention was to use an || instead of &&, a mistake that can be made by both humans and AI systems that author policies.

// This policy cannot allow any requests due to logical errors
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  principal.getTag("customer_tier") == "Platinum"
}
unless { context.input.refundAmount > 1000 };

Similarly, Cedar Analysis can detect policies that always allow a given action, usually an indication of an overly permissive policy. For example, the following policy will allow all ApplyBulkDiscount requests because any order quantity will either be greater than or equal to 100 or less than 100.

// This policy allows all ApplyBulkDiscount requests
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  context.input.orderQuantity >= 100 ||
  context.input.orderQuantity < 100 ||
  (principal.hasTag("customer_tier") &&
   principal.getTag("customer_tier") == "Platinum")
};

Detecting such logical errors isn’t easy for humans, and can’t be done by pattern matching: you need the formal rigor of mathematical analysis, which is exactly what Cedar Analysis does.

Detecting policy conflicts: Cedar Analysis can also analyze the entire policy set to detect inconsistencies between different individual policies:

// These policies conflict - Analysis will detect the subtle issue
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  context.input.refundAmount < 100
};

forbid (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  ["Gold", "Platinum"].contains(principal.getTag("customer_tier")) &&
  context.input.refundAmount < 500
};

The permit policy allows gold customers to process refunds less than $100, while the forbid policy blocks gold customers (and platinum customers) from processing refunds less than $500. Because forbid overrides permit in Cedar, the forbid policy would block all gold customer refunds despite the permit policy.

Comparing policy changes: When updating policies, Cedar Analysis can also determine the exact impact of a change. Consider the following update to the unless clause (the policy lines with + have been added and those with - have been removed): we now block ApplyBulkDiscount only when the product type is limited_edition and the quantity exceeds 200.

 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ProcessRefund",
   resource
 )
 when
 {
   context.input.refundAmount < 500
 };
 
 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ApplyBulkDiscount",
   resource
 )
 when
 {
   context.input.orderQuantity >= 50
 }
 unless
 {
-  context.input.productTypes.containsAny(["limited_edition"])
+  context.input.productTypes.containsAny(["limited_edition"]) &&
+  context.input.orderQuantity > 200
 };

At first glance, adding a condition to the unless clause might seem more restrictive. In fact, it’s the opposite: narrowing when the unless applies means the permit now covers more requests. For example, an order of 73 units of a limited_edition product would have been blocked before but is now allowed. Cedar Analysis can automatically detect this and generates the following table showing the difference in permissiveness between the original policy set and the updated one:

Principal type

Action

Resource type

Status

OAuthUser

ProcessRefund

Gateway

Equivalent

OAuthUser

ApplyBulkDiscount

Gateway

More permissive

In the preceding example, the analysis tells us that the updated policy allows allows exactly the same ProcessRefund requests, but allows more ApplyBulkDiscount requests.

This formal verification capability is essential when agents operate autonomously and can affect the real world. Organizations need mathematical certainty that their policies will behave as intended.

Deterministic behavior for reliable governance

Unlike probabilistic AI models, enterprise security requires deterministic guarantees. Cedar policies always produce the same authorization decision for identical requests, regardless of evaluation order or system state. Cedar’s default deny, forbid wins, no ordering semantics help ensure predictable behavior.

// Policy evaluation order does not affect the authorization decision
permit(
    principal,
    action == AgentCore::Action::"ProcessRefund",
    resource
) when {
    context.input.refundAmount < 500
};

forbid(
    principal,
    action == AgentCore::Action::"ProcessRefund", 
    resource
) when {
    context.input.orderDate.offset(duration("90d")) < context.system.now
};

Whether the permit or forbid policy is evaluated first, a refund request over $500 will always be denied, and any refund issued more than 90 days after the order date will also be denied. This predictability gives enterprises confidence in their agent governance.

From policies to production

By choosing AgentCore Policy and Cedar, organizations can deploy autonomous agents with policies they can reason about mathematically, not only hope the agents work correctly. Cedar’s combination of expressiveness, readability, and formal verification means that you can design agents with the flexibility needed to function and the certainty security teams demand.

Automated reasoning has already proven its value across AWS, from AWS IAM Access Analyzer verifying access policies to provable security for network configurations. Applying these same techniques to agentic AI is a natural extension: as agents take on more responsibility, the need for mathematically grounded guarantees only grows. The neuro-symbolic approach we’ve described in this post—combining LLM flexibility with the rigor of automated reasoning—points toward a future where agents can be both more autonomous and more trustworthy, because the verification keeps pace with the autonomy.

Learn more

Policy is now available as part of Amazon Bedrock AgentCore Gateway. To learn more about Cedar and its capabilities, visit the Cedar website, try the Cedar playground, or join the Cedar community on Slack.

For more information about Policy in Amazon Bedrock AgentCore Gateway, visit the AWS documentation or explore the AgentCore Gateway console.

If you have feedback about this post, submit comments in the Comments section below.
Liana Hadarean

Liana Hadarean

Liana is a Principal Applied Scientist at AWS. She has worked on the code analysis tools that power Amazon Q Java security detectors, and is now a contributor to the Cedar policy language.

John Tristan

Jean-Baptiste Tristan

Jean-Baptiste is a Senior Principal Applied Scientist at AWS Agentic AI where he works on neurosymbolic AI and agentic safety.

Плаваща България и съдбата на „Калиакра“

Post Syndicated from Веселин Златков original https://www.toest.bg/plavashta-bulgariya-i-sudbata-na-kaliakra/

Плаваща България и съдбата на „Калиакра“

Поне половината българи бъркат глаголите плувам и плавам или ги използват като синоними – просто както им звучи по-добре. Може и да не съм прав в това обобщение, но такива са наблюденията ми. Понякога грешките са направо трагикомични, като онова прословуто съобщение на пресцентъра на правителството на Кирил Петков, в което се предупреждаваше, че към българския бряг плуват (не стана ясно в какъв стил – гръб, кроул или кучешката) морски мини и може да навлязат в нашата екватория (такава дума няма, има акватория – водно пространство, както вече е било поправено на сайта, след като някои медии обърнаха внимание на грешката).

В много репортажи корабите акУстират вместо да акОстират и за да не стават грешки, случвало се е и направо да паркират на пристанищата. Като цяло морската култура на българите е доста слаба, може би с изключение на кулинарния раздел в нея. 

А иначе, много българи плуват – от легендата Петър Стойчев до участниците в „Игри на волята“, и можем да кажем, че плуващата България се разраства.

Новите проблеми на Варна
Варна като разказ за пропуснат шанс и за системно разминаване между амбиция и реалност. В града се строи повече, отколкото се живее, обещава се повече, отколкото се изпълнява. Между морето, имотите и провалените проекти наднича въпросът „Къде потъна потенциалът?“. От Веселин Златков.
Плаваща България и съдбата на „Калиакра“

С плаващата България нещата са малко по-различни 

Като пълноправни европейци ние вече имаме достъп до прословутите „три морета“, както и до всички останали, за които националистите ни не са се и осмелявали да мечтаят. Хората с възможности си купуват яхти или си организират почивки на катамарани в Егейско море, но някак си все сме далече от претенцията да сме морска нация. 

Ех, само ако имаше нещо, което да послужи за символ на българската морска идея; което да е за младите; нещо, което да ги научи да познават и усещат същността на морето и да влязат в кожата на знаменитите световни мореплаватели, откриватели и изследователи…

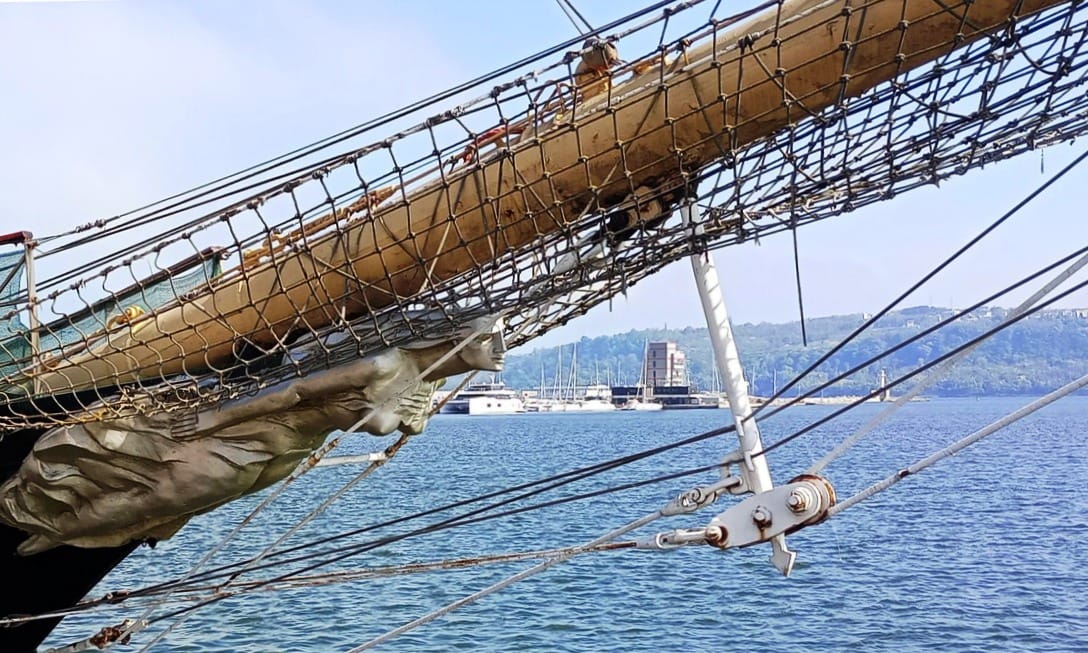
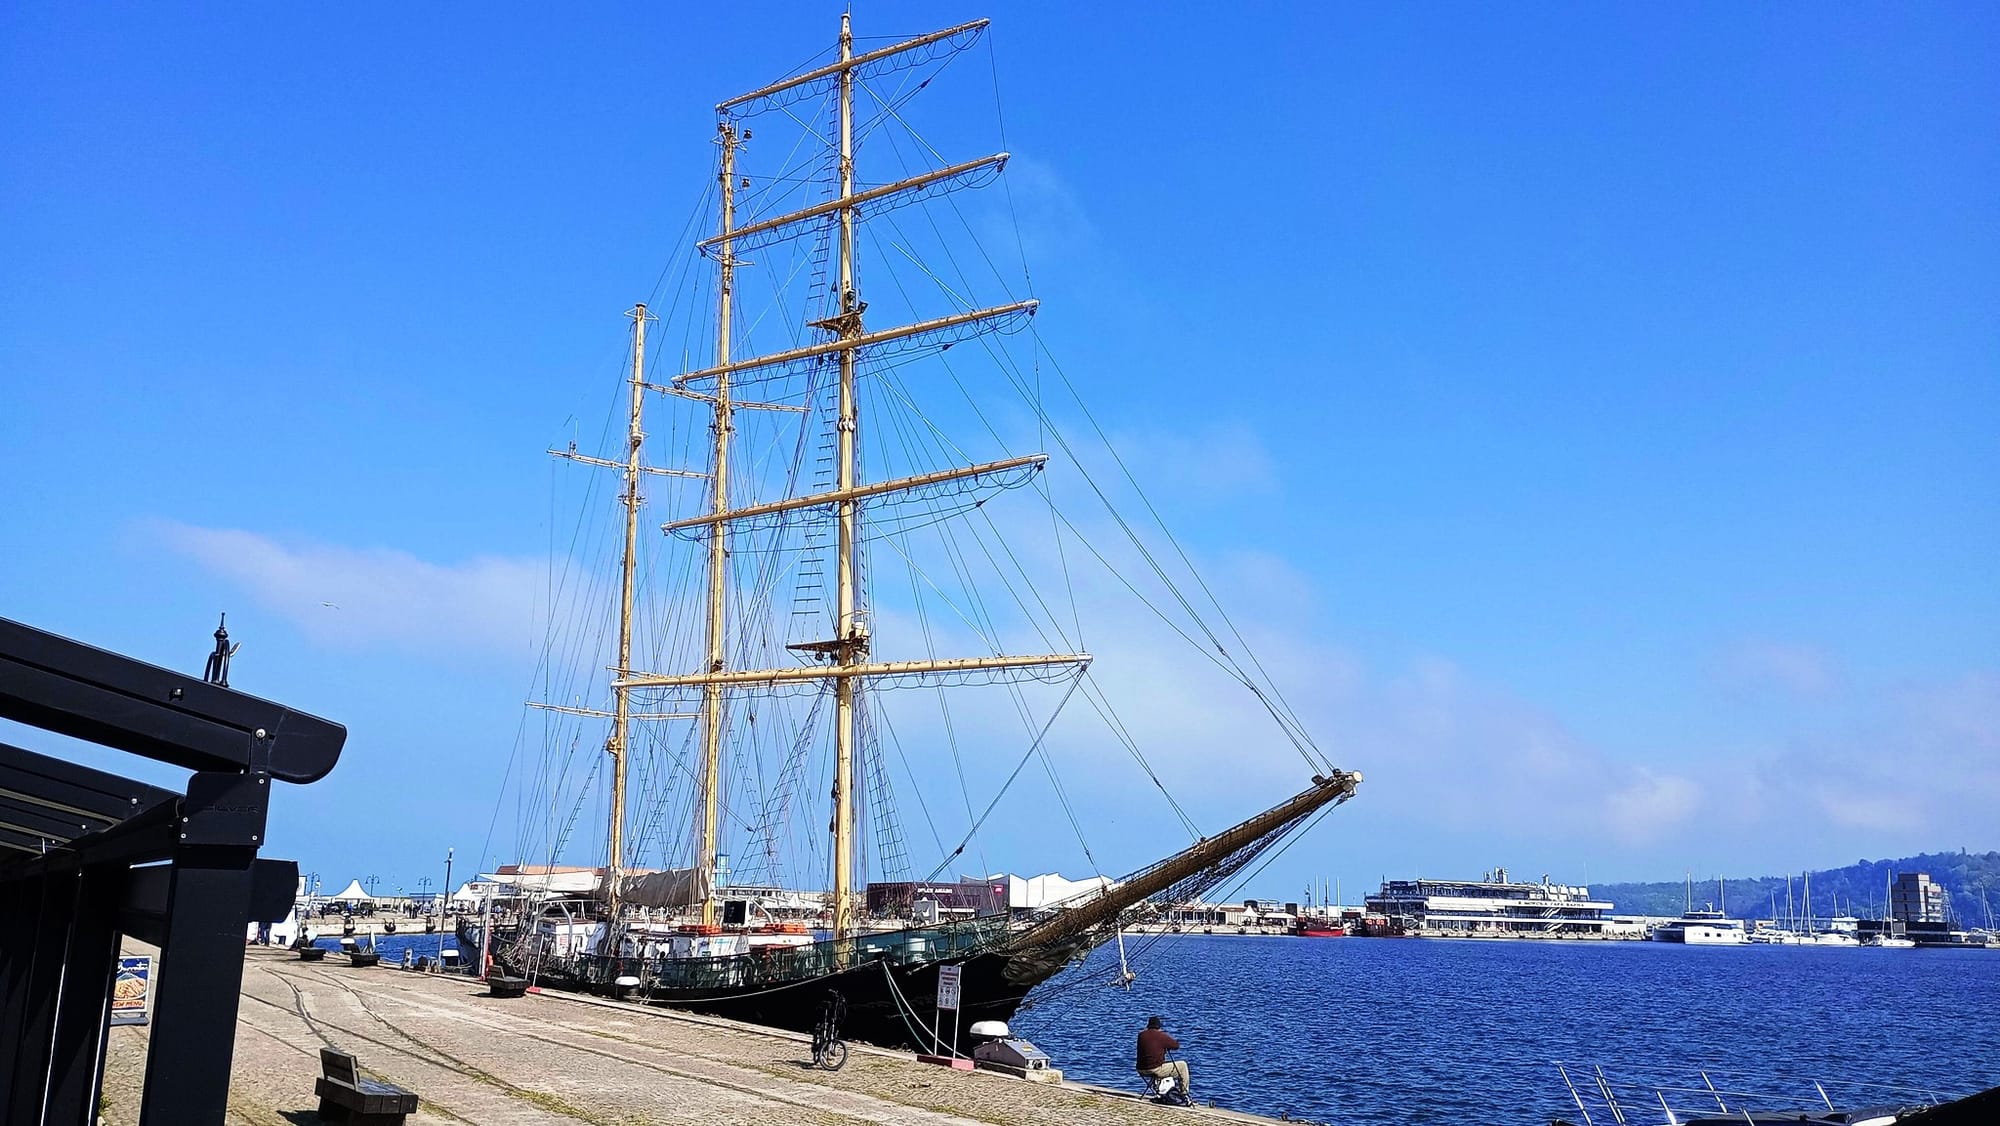
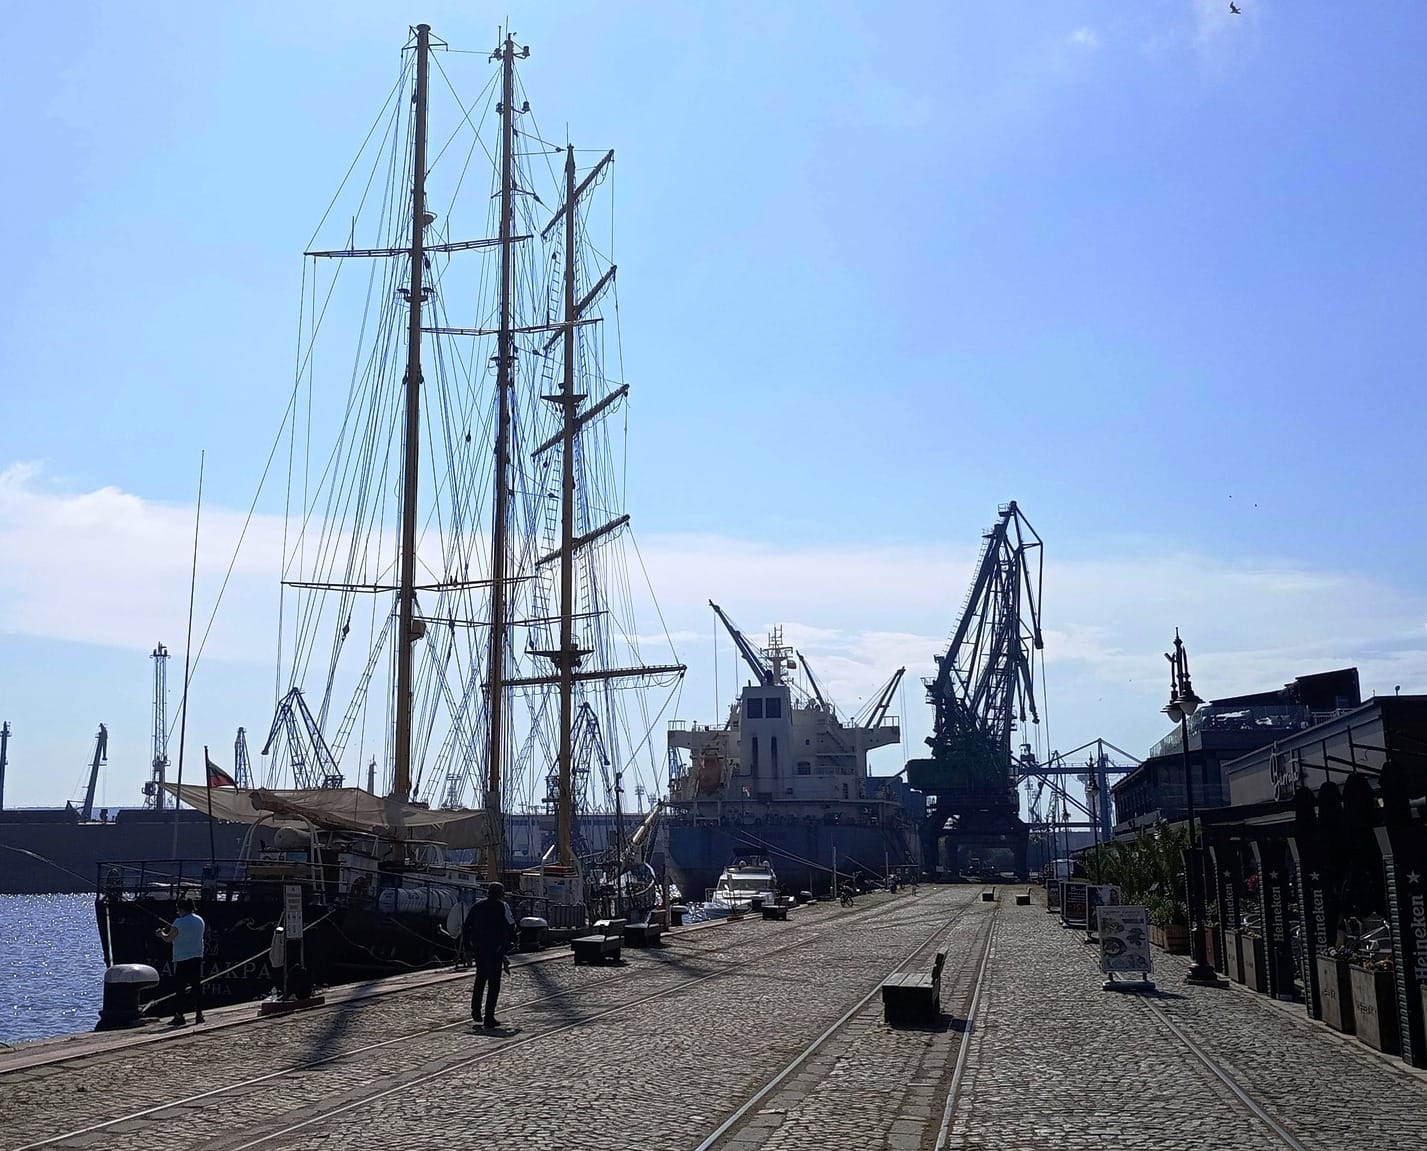
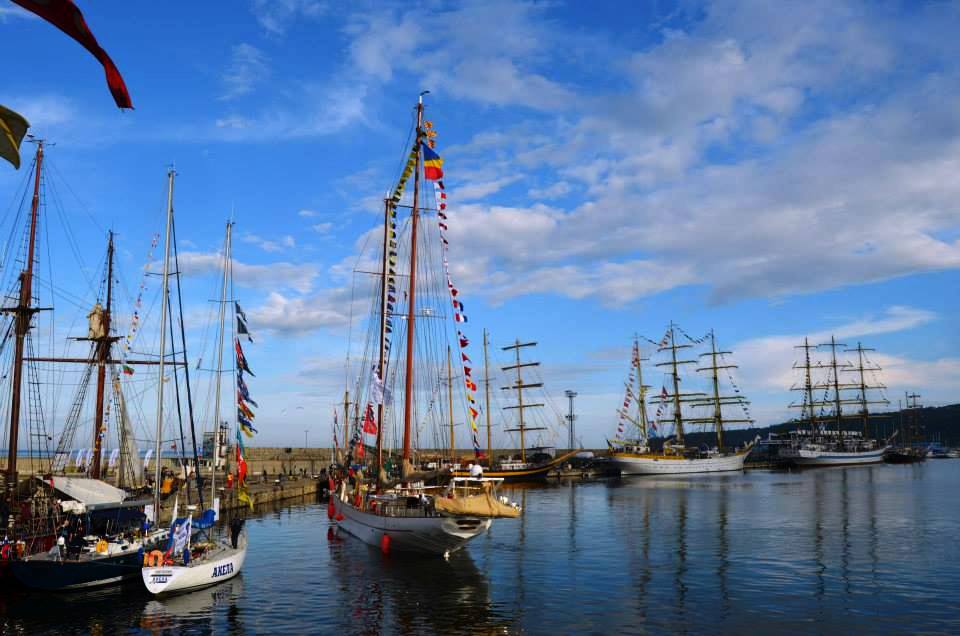
Има такова нещо. Красив кораб с високи мачти. Вързан е на кея на пристанището във Варна. Използва се за декор и допълнителна площ с маси към популярен ресторант. И за частни партита, когато някой реши да се изфука. 

Ситуацията, в която се намира българският учебен ветроходен кораб „Калиакра“ в последните години, може да се сравни само с това някой училищен физкултурен салон през лятната ваканция да се ползва за стриптийз бар. 

Срамното не е това, че на палубата на славната ни баркентина се разнасят чинии и чаши. Срамното е, че „Калиакра“ не плава. От много години. 

„Калиакра“ е построена през 1983–1984 г. в полските корабостроителници в Гдиня и Гданск по проект на изключителния корабен дизайнер Зигмунд Хорен. Учебният ветроход има две по-стари „сестри“ – „Погория“ и „Искра II“. Те са създадени със същата цел: да служат за учебна база на курсанти и кадети, в случая с „Погория“ – 14-годишни бъдещи моряци. 

С направените подобрения на базовия проект „Калиакра“ се превръща не само в красив, но и в много бърз ветроход, а ентусиазираните български ветроходци започват да печелят победи над далеч по-опитни съперници от всички големи морски нации. „Калиакра“ постига и двете цели, заради които социалистическата държава я е поръчала. От една страна, обучението на курсантите от ВВМУ „Никола Вапцаров“ минава на ново ниво, а от друга – и това в крайна сметка е по-ценното, – България влиза в престижното общество на страните, които имат учебни ветроходи. 

Плаваща България и съдбата на „Калиакра“
Снимка: Веселин Златков

„Калиакра“ не идва на празно място – през 70-те и 80-те години на миналия век българското ветроходство има своите исторически успехи. На първо място, разбира се, е истинският подвиг на капитан Георги Георгиев, който става първият българин, направил солова обиколка на света с яхта. Постижението му с „Кор Кароли“ е записано в Книгата на рекордите „Гинес“ заради необичайния маршрут през Панамския канал. 

Николай Джамбазов строи сам своята „Тангра“ и прави околосветското си самотно плаване напук на спънките от партийни лидери, които се опитват да го спрат. Дончо и Юлия Папазови обикалят света с малката си дъщеря Яна на борда на „Тивия“, а книгите за пътешествията им стават вдъхновение за деца и възрастни. 

Българската баркентина обаче придава съвсем различен контекст за страната ни в общността на морските държави 

В епохата на т.нар. развит социализъм Народна република България има ужасна нужда от приходи не в преводни рубли, а в долари, и корабоплаването, международните превози и търговията са очевидният начин да си ги осигури. Тъй като морският бизнес не се съобразява с правилата на Източния блок, Държавно параходство „Български морски флот“ (БМФ) трябва да се държи като морска компания – по подобие на всички останали. Като маркетингова стратегия БМФ финансира плаващата под ветрила България, като това довежда и до огромен успех в спортното ветроходство на най-високо ниво. Яхта „Булкон стар“ (носеща името на контейнерната компания на БМФ „Булкон“) завършва първа в класа си в трансатлантическата регата „Тустар“ благодарение на майсторството на шкипера Светлозар Тенев и екипажа му Васил Попов.

Плаваща България и съдбата на „Калиакра“
Снимка: Веселин Златков

На този фон „Калиакра“ става най-големият посланик на все по-уверено плаващата България – не само по света, а и в съзнанието на българите, традиционно резервирани за морската идея като нещо повече от лято и плаж. Както имаме космонавти и български флаг на Еверест, така имаме ветроходен кораб, който трупа престиж в световните океани и морета. 

„Калиакра“ става мечта за хиляди български деца и младежи, жадни за приключения

Междувременно през 1986 г. по телевизията се появява екранизацията на шедьовъра на Братя Мормареви „Васко да Гама от село Рупча“, от който става ясно, че един тийнейджър може да е влюбен в морето и плаването, колкото и в Тинчето. А Павел Поппандов просто „заковава“ образа на българския пампорджия. 

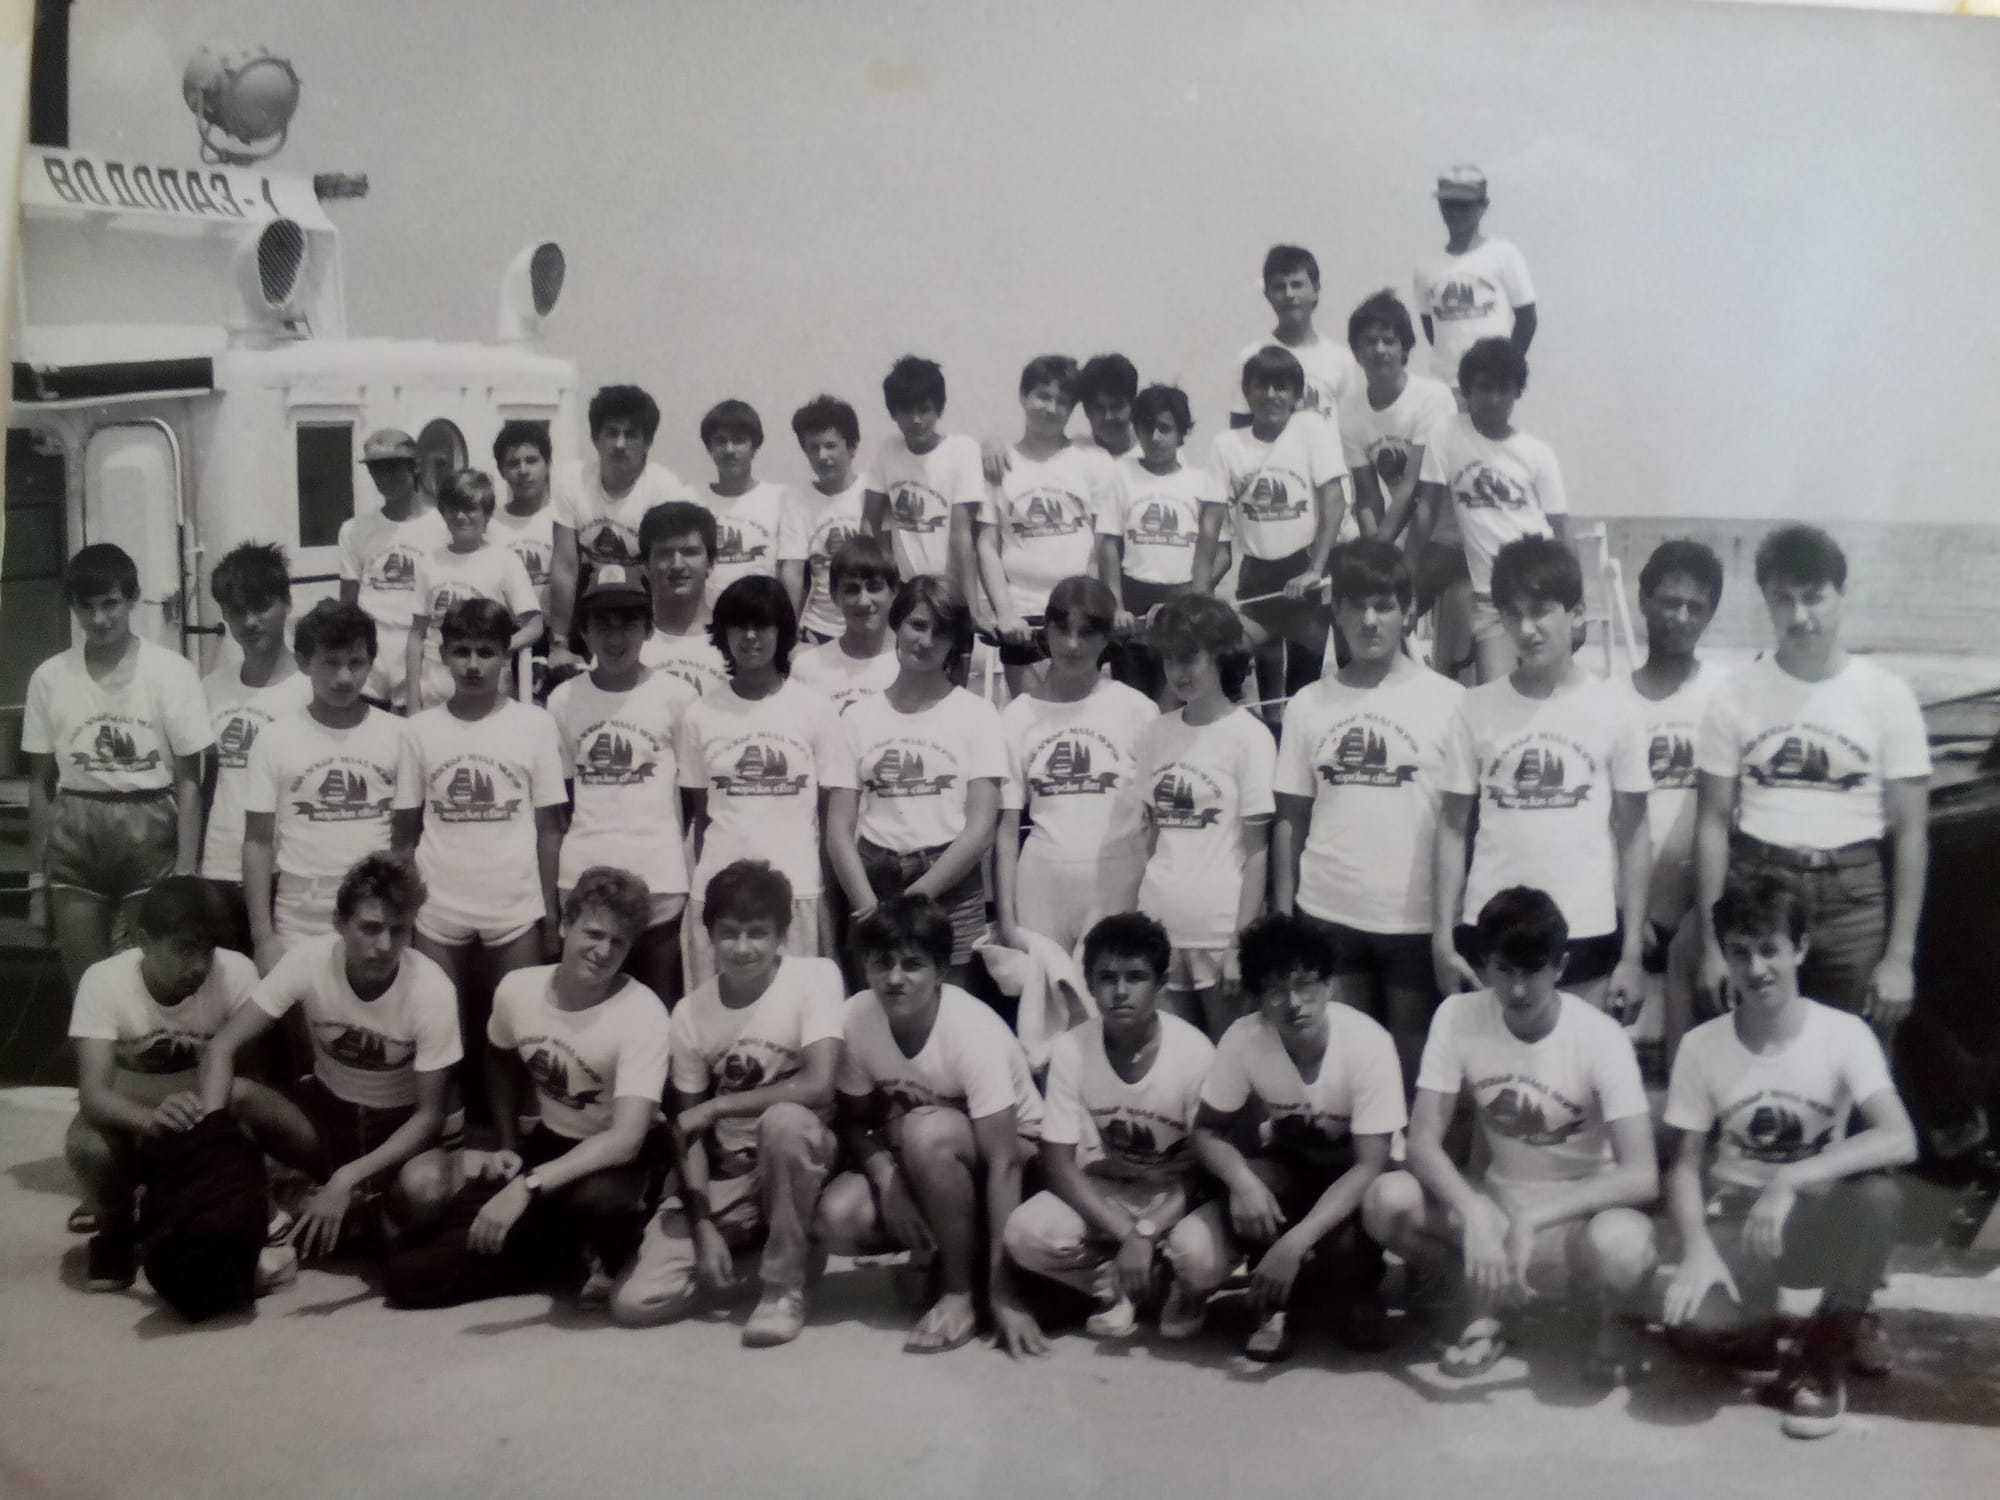
Тук трябва да отворя скоба, в която вероятно ще стане ясно защо смятам съдбата на „Калиакра“ за важна. За мен плаването на борда ѝ беше мечта, която се сбъдна в най-точния момент. През 1987 г. БМФ и легендарното (не само с тематиката си, но и с дизайна и качеството на печат) списание „Морски свят“ организира конкурса „Най-добър млад моряк“. Той беше за 14-годишни момчета и момичета, имаше теоретична и практическа част, с плуване и гребане, както и връзване на морски възли. С голям късмет влязох в групата, която стигна до наградата – плаване с „Калиакра“ за 10 дни в началото на учебната година.

Катеренето по мачтите, прибирането и спускането на ветрилата, спането в тясната койка, нощната тревога за смяна на курса, даже лъскането на палубата и другите всекидневни дейности на „Калиакра“ ме промениха напълно. Може би не за цял живот, но със сигурност в точния момент, когато се изгражда личността на един тийнейджър. Нищо не създава такова усещане за екипна отговорност, както тегленето на въжета, за да поеме корабът в правилната посока…

Това е същността на „Калиакра“ – да възпитава. Но за да го прави, трябва да плава. Като стационарен тренажор, до какъвто е сведена в момента като учебен кораб, тя не може да изпълни главната си функция.

Плаваща България и съдбата на „Калиакра“
Снимка: Веселин Златков

Междувременно морска България преживя десетилетия на твърде противоречиви промени. По отношение на ветроходството станаха невероятни неща, появи се втори ветроход – „Роял Хелена“, частен кораб, копие на „Калиакра“, построен от българска частна корабостроителница. След поредица забележителни плавания в крайна сметка втората българска баркентина беше продадена на Доминиканската република, където на нея се обучават тамошните млади моряци. 

Заради престижа на „Калиакра“ в общността на учебните ветроходни кораби Варна три пъти беше домакин на регатата „Тол шипс“, най-престижното морско събитие в света. А после… После изведнъж на държавата сякаш ѝ омръзна да има морска политика и всичко замря. 

Залезът на варненския популизъм
Варна не е монополист в местното производство на популисти, но често им дава първата сцена. Местни конфликти, бизнес интереси, недоверие към центъра и вкус към политическия тарикатлък превръщат „варненското“ в удобен модел за по-големи амбиции. От Веселин Златков.
Плаваща България и съдбата на „Калиакра“

Параходство БМФ беше приватизирано през 2008-ма, по обща оценка – много успешно. През 2019-та България изгуби своя морски флаг, след като вече частното параходство беше регистрирало повечето си кораби в Малта и така флагът ни стана „невидим“ за Парижкия меморандум – организацията, която се занимава с пристанищния контрол на корабите. 

А „Калиакра“ спря да плава и стана това, което е днес – декор и морско сепаре на крайбрежен ресторант. 

Плаваща България и съдбата на „Калиакра“
Снимка: Веселин Златков

Разбира се, това не е последен пристан за българската морска идея

Научноизследователският кораб „Св. св. Кирил и Методий“ върна морския престиж на страната ни със своите плавания до Антарктида. Максим и Стефан Иванови и тяхното шеметно гребно пътешествие с „Неверест“ показаха ясно, че има българи, които не се страхуват да предизвикат стихиите на океана и да се срещнат с тях лице в лице. Има и още примери, макар и не много. Но това са единици, по-скоро изключения от правилото, че държавата ни няма никаква идея как да развива морския си сектор, и честно казано, това е последната ѝ грижа. 

Нека предложа един факт, по който можем да разсъждаваме. Общата дължина на българската държавна граница е 2245 км. От тях 848 км са водни пътища – 378 км по брега на Черно море и 470 км по Дунав. Поправете ме, ако греша, но България може и трябва да плава повече. Добро начало на този път ще е връщането на „Калиакра“ там, където ѝ е мястото – в морето, в океана, под ветрила и с екипаж от млади хора, които самото плаване ще превърне в по-силни и по-осъзнати личности, променяйки живота им – ако не завинаги, то със сигурност в точния момент.

The collective thoughts of the interwebz