At the end of last year, Professor Becky Francis published her long-awaited Curriculum and Assessment Review for England, accompanied by the UK government’s official response. Buried within that response — and not actually proposed in the Review itself — was a notable commitment: to “explore introducing a new Level 3 qualification* in data science and AI, to ensure that more young people can secure high-value skills for the future and that we cement the UK’s position as a global leader in AI and technology.”
This announcement reflects a growing global recognition that young people need more than basic digital literacy — they need a deeper understanding of data, automation, and the rapidly evolving capabilities of AI. Countries around the world, from Singapore to the United States, are already wrestling with how to embed AI education into secondary schooling. England now joins that international conversation.
Why AI education matters
AI is an everyday technology now. Young people interact with AI systems constantly, often without realising it. Whether they pursue careers in medicine, engineering, the creative industries, or public policy, they will need a foundational understanding of how AI systems work, what their limitations are, and the ethical implications around them.
Yet in England — and in many education systems globally — very few students receive formal teaching about AI. The English national curriculum makes no explicit reference to AI, and specifications for exams taken at the end of high school include only scattered mentions. This gap leaves young people navigating one of the most transformative technologies of their generation with limited guidance.
Exploring a qualification: Opportunities and challenges
In 2025, we joined forces with Professor Lord Lionel Tarassenko, one of the UK’s foremost researchers in AI and machine learning, and Simon Peyton Jones, a world-renowned computer scientist and long-time champion of computing education. Together with teachers, school leaders, universities, industry specialists, and exam boards, we have been exploring how we might begin to close the emerging gap in AI and data science education for 16- to 18-year-olds.
Over the past eight months, this collaboration has allowed us to refine our shared thinking and gather insights from a wide network of experts and practitioners. We are delighted that England’s Department for Education has recognised the potential of this work by appointing us to draft the subject content for a possible new A level in Data Science and AI.
We are delighted that England’s Department for Education has recognised the potential of [the work we have done] by appointing us to draft the subject content for a possible new A level in Data Science and AI.
Designing a qualification of this kind raises important questions — not just for the UK, but for any country considering a similar path.
What knowledge and skills should young people gain from the qualification?
A meaningful qualification must go beyond the use of tools. It should help students understand data literacy, model behaviour, bias, ethics, and the societal implications of AI. Balancing technical understanding with critical thinking is challenging but essential.
How do we ensure the qualification is accessible and inclusive?
AI should not become the preserve of already-advantaged students. Any qualification must be designed with equity in mind, recognising differences in school capacity, teacher expertise, and students’ prior experience.
How do we support teachers to deliver the qualification?
Teacher professional development is a major challenge worldwide. Delivering a qualification in AI will require confidence with concepts that are not yet common in teacher training. Sustainable delivery models — supported by high-quality resources and professional development — will be crucial.
What form should the qualification take?
There is an active debate about whether the best route for students in England is a high-stakes qualification or a supplementary course that broadens a core programme of study:
An A level provides structure, national recognition, and clear progression into higher education or employment.
An Extended Project Qualification (EPQ) may offer more flexibility, allowing students to explore AI through research or practical investigation without requiring schools to timetable a full qualification.
Different countries will make different choices based on their systems, but the underlying questions are the same: how do we create something rigorous, scalable, and future-proof?
What we’ve learned so far
In October, the Foundation hosted a workshop with representatives from schools, industry, universities, exam boards, and the Department for Education. Together, we explored key questions including:
How do we make a qualification compelling – both for students who choose it and for schools that offer it?
What delivery models will genuinely support teachers to succeed?
The feedback we received has been invaluable and will continue to shape the next stage of development. We believe the UK has a significant opportunity to contribute meaningfully to the global conversation about AI education. You can read the latest version of our discussion paper here.
A global call for insights
Although the current proposal focuses on England, the underlying challenge is international: how do we prepare young people everywhere to engage thoughtfully and confidently with AI?
We would love to hear from educators, researchers, and policymakers across the world:
Do you know of any successful qualifications or programmes for 16- to 18-year-olds that centre AI or data science?
What lessons should countries learn from each other?
To share your ideas or feedback, please get in touch. We’d be delighted to learn from your experience as this important work progresses.
* Level 3 in England is the stage of learning for 16- to 19-year-olds, typically ending in qualifications that pave the way for higher study or advanced apprenticeships.
The extensible scheduler class (sched_ext)
allows the installation of a custom CPU scheduler built as a set of BPF
programs. Its merging for the 6.12 kernel release moved the kernel away
from the “one scheduler fits all” approach that had been taken until then;
now any system can have its own scheduler optimized for its workloads.
Within any given machine, though, it’s still “one scheduler fits all”; only
one scheduler can be loaded for the system as a whole. The sched_ext
sub-scheduler patch series from Tejun Heo aims to change that situation
by allowing multiple CPU schedulers to run on a single system.
Welcome to our second quarterly Network Stats report covering Q4 of 2025. Along with Drive Stats and Performance Stats, Network Stats pulls back the curtain on real-world infrastructure data, particularly how network-level analytics reflect emerging AI industry trends and usage patterns.
Get more Network Stats (and the details of the dataset)
If you are curious about what metrics we’re recording and how we classify data in this series, check out the details outlined in our Q3 2025 Network Stats report.
One of the roles of the Network Engineering (NetEng) team at Backblaze is to monitor how traffic moves into, out of, and across our platform—not just day-to-day, but over time as customer behavior and industry dynamics evolve. Right now, few forces are reshaping networks faster than AI.
With the launch of B2 Overdrive in April 2025, we built a direct, high-performance path between our storage layers and neoclouds where processing, inference, and modeling take place. It has given us a front-row seat to the impact of AI and how network behavior is changing with it. This quarter, in addition to our regular data analysis, I’ll walk through where AI-driven traffic is concentrated, how ingress and egress patterns showed up, and what the findings say about where AI infrastructure might be headed next.
Continue the conversation
Join us live for the Q4 2025 Network Stats webinar Wednesday, February 4, 2025 at 10:00 a.m. PT / 1:00 p.m. ET. We’ll explore where AI traffic concentrates, how high-magnitude data flows behave, and what early indicators suggest about the future of AI-native infrastructure design.
Can’t make it live, or reading this article after-the-fact? Sign up anyway and catch the recording on demand.
Brave new market
AI workflows don’t just need a place to store data, they need to be able to move it quickly, easily, and nearly constantly for short bursts. Large, multi-petabyte datasets are ingested, transformed, exported for training, pulled back for evaluation, and periodically refreshed as models evolve.
Backblaze plays a key role at both ends of that lifecycle. We serve as a durable storage layer for the initial data ingestion, and as the high-throughput source feeding model training, evaluation, and validation to whatever best neocloud is suitable at the moment. Once that model has been trained, it needs to be stored, served, and periodically retrained, where we serve as the storage medium.
This quarter, we saw a large amount of traffic between Backblaze, neoclouds, and traditional hyperscalers for processing concentrated across the months of June to November. This reflects large-scale ingestion events followed by intensive data manipulation and model-related egress.
From a network perspective, this represents a meaningful shift from diffuse, internet-style traffic patterns to large, high-bandwidth flows between a smaller set of endpoints typical of AI-centric infrastructure.
The neocloud slice
The defining theme of the quarter is “new:” new AI-oriented workflows, new traffic patterns, and leading indicators of new infrastructure trends.
The stacked area graph below shows total traffic by network type over time. While content delivery network (CDN), hosting, and internet service provider (ISP) traffic stayed largely within historical norms reflecting steady-state usage patterns like content delivery, web hosting, and traditional backup workflows, two slices stand out:
Migration traffic: We saw a notable increase in migration traffic from August through October. This classification reflects an influx of data into our network over fiber connections we have in the data centers to cost effectively migrate large amounts of data over private links, not using the public Internet.
Neocloud traffic: We saw a sharp increase in July through November, peaking in October.
Monthly view of all bits transferred to each network type
What do we think is happening? Taken together, these patterns suggest a familiar AI lifecycle: large datasets consisting of assets like images, videos, and metadata are ingested and consolidated then exported for training and experimentation. Now, those assets can be periodically updated as new assets are added and generated models and stored. We see that heading into the new year, the overall baseline has increased indicating a new normal.
Quick terminology refresher
Regions
US-West: Our largest and longest-running region
US-East: Region with the most observed proximity to neocloud infrastructure
CA-East: Our newest region in Canada.
Network Types
CDN: Networks that use Backblaze as an origin store for content delivery
Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks
Hyperscaler: Large, traditional cloud providers
ISP Regional: Local or regional ISPs, think of these as the “last mile” paths as these networks are very close to customer equipment and efficient
ISP Tier1: National or international ISPs that carry our traffic long distances
Neocloud: AI -focused compute networks
Migration: Network links that we use for large-scale data onboarding
Heatmaps: Where AI traffic concentrates
To better understand where AI activity is happening, we thought it would be interesting to isolate the different Backblaze regions and to view concentrations of metrics visualized through heatmaps. We’re going to look at the following three dimensions:
Total traffic volume: Where did we send and receive the most traffic?
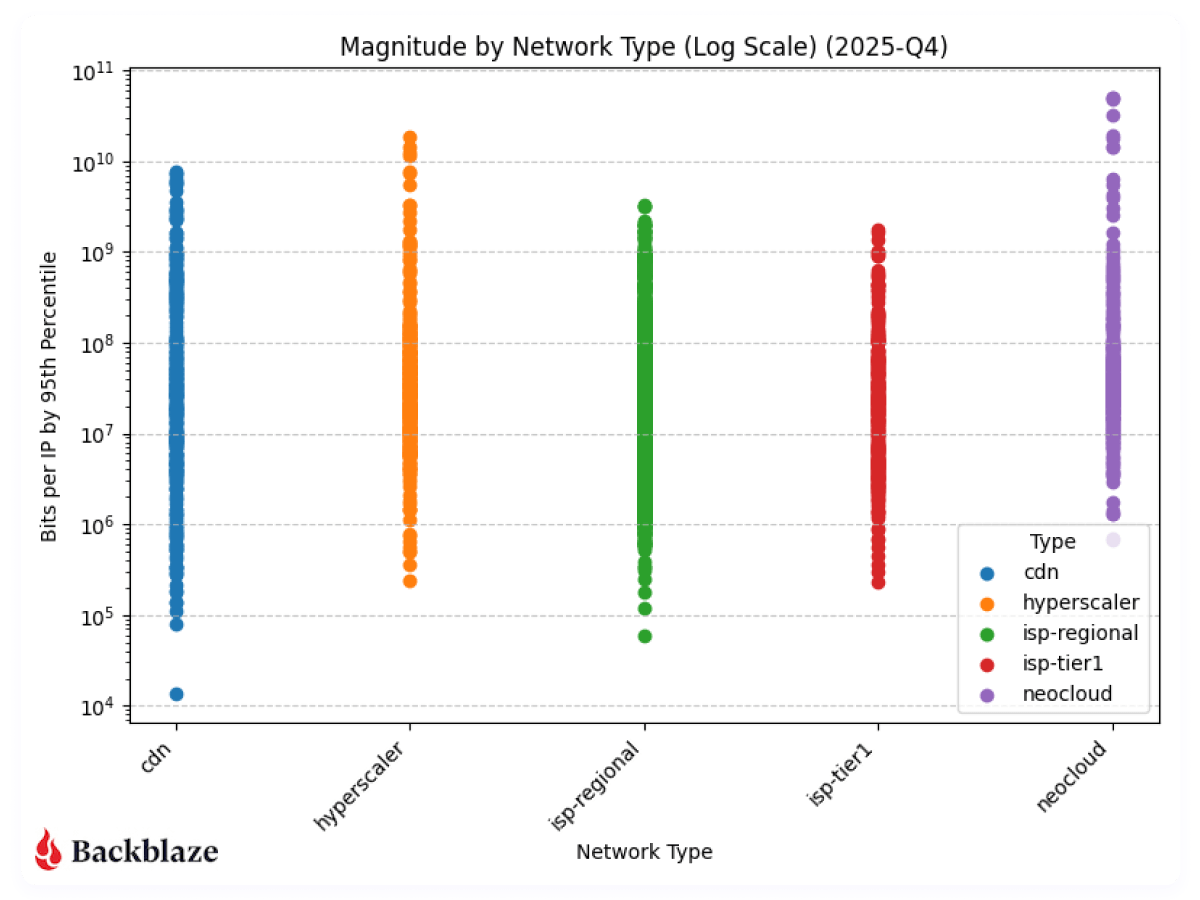
Magnitude: Where were the data transfers with the most bits per unique IP address?
Uniqueness: What does the number of distinct IP addresses look like?
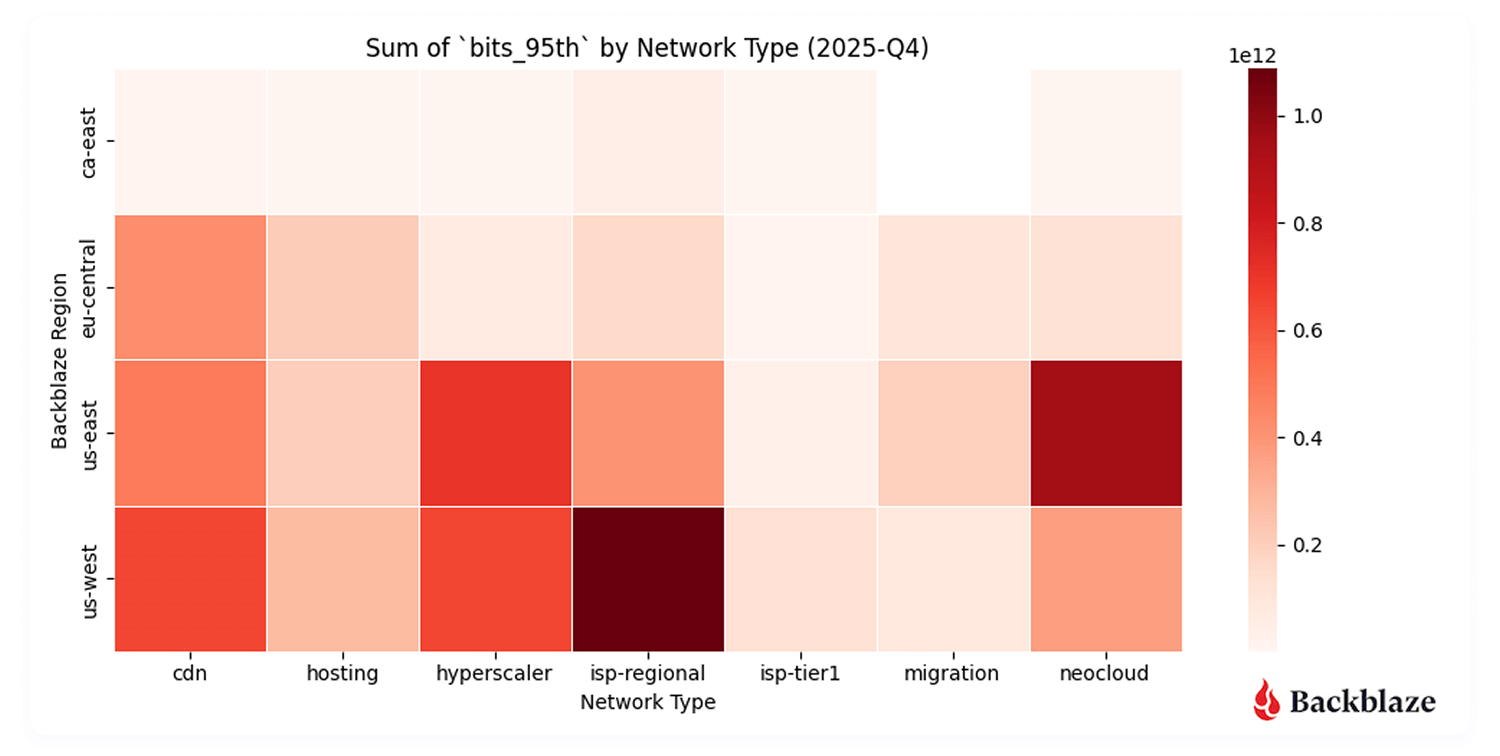
Heatmap #1: Where did we send and receive the most traffic?
Unsurprisingly, US-West ISP-Regional traffic dominates in total traffic volume. This region has the largest data center footprint behind it, with connectivity to internet exchanges (IX) such as Equinix-IX that were brought online in 2023. Internet exchanges bring us closer to consumer networks, where we can deliver traffic with lower latency.
More interesting, however, is the US-East neocloud concentration. Our flow data shows neocloud activity clustering in regions including Chicago, Dallas-Houston, Denver, New York, Northern Virginia (Reston/Ashburn corridor), and Atlanta—skewed more towards the East Coast where there’s dense AI compute availability.
From a performance standpoint, this makes sense. It’s important to keep latency (the time between the source and destination) lower to achieve consistent high bandwidth rates for AI data transfers. For now, that gravity is pulling activity towards the East coast.
Total number of bits transferred across our regions to each network type
Will neocloud traffic concentrations shift over time? Since this is our first quarter with a full dataset, it’s a bit early to draw long-term conclusions. But this is exactly the kind of trend we’ll be tracking. Stay tuned for future Network Stats reports.
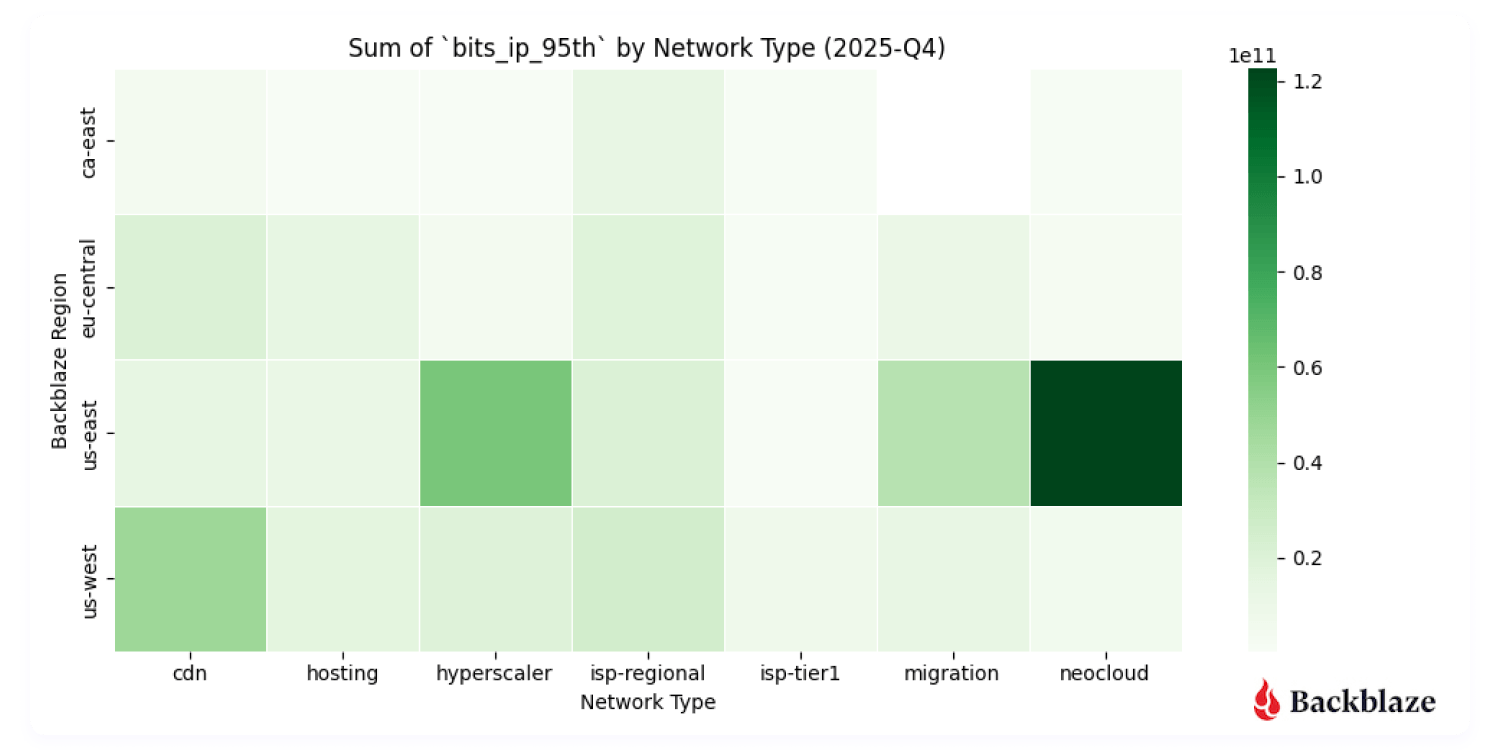
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?
Another metric we record is bits per IP or what we termed in our last report “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:
High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
High volume, few IPs: More difficult, but more interesting, from a NetEng perspective.
Magnitude transferred across our regions to each network type
With B2 Overdrive, we routinely support client transfers starting at 100Gbps up to 1Tbps of throughput.These high-magnitude flows show up clearly in the data, especially in regions serving AI-heavy neocloud endpoints. Seeing these patterns emerge in the data validates that customers are actively using the platform the way it was designed.
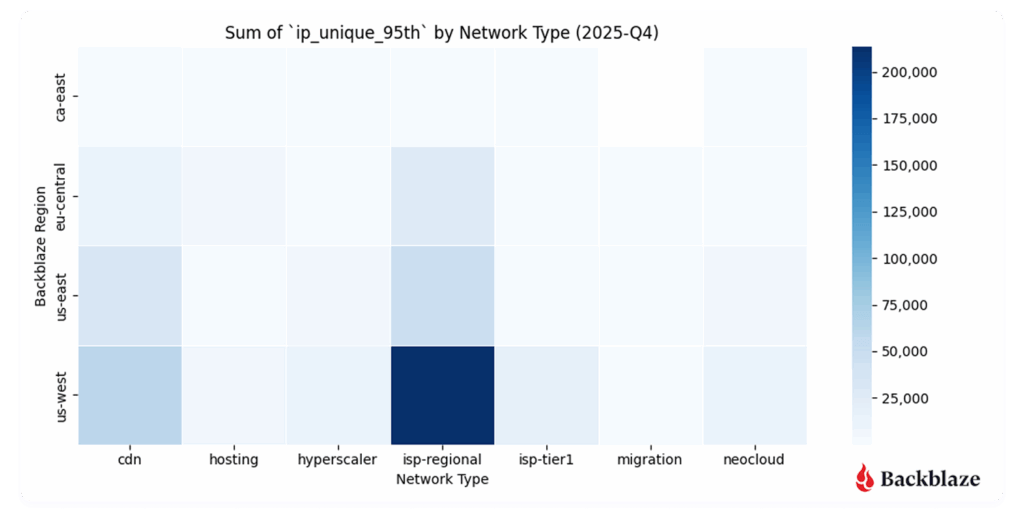
Heatmap #3: How many unique addresses do we interact with?
Uniqueness—measured by the number of distinct IP addresses per network type—adds another dimension to the story.
US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
This contrast reveals a broader trend: AI networking is less about many-to-many communication and more about sustained high-throughput relationships between specialized systems.
Communication uniqueness across our regions to each network type
Summary: Early indicators of an AI-native network era
This quarter represents an early but important snapshot of how AI is reshaping network behavior:
AI-driven traffic is concentrated and heavy (not groundbreaking news by any means, but interesting to see it played out on a network).
Neocloud connectivity is a defining feature of data movement today.
Data gravity is pulling storage, compute, and network design into tighter alignment.
This is our first look at these patterns specifically. As we gather more quarters of data, we’ll be watching closely to see how cyclical neocloud activity becomes, how regional concentrations shift, and how the growing ecosystem of AI-focused ISVs continues to change the shape of the network.
Quarter over quarter data
Last quarter we started capturing data and metrics that we were interested in tracking over time. This represents our first full quarter of data as we only started tracking in August of 2025, so it’s still early to start to see trends, but we’re including the visualizations for fidelity.
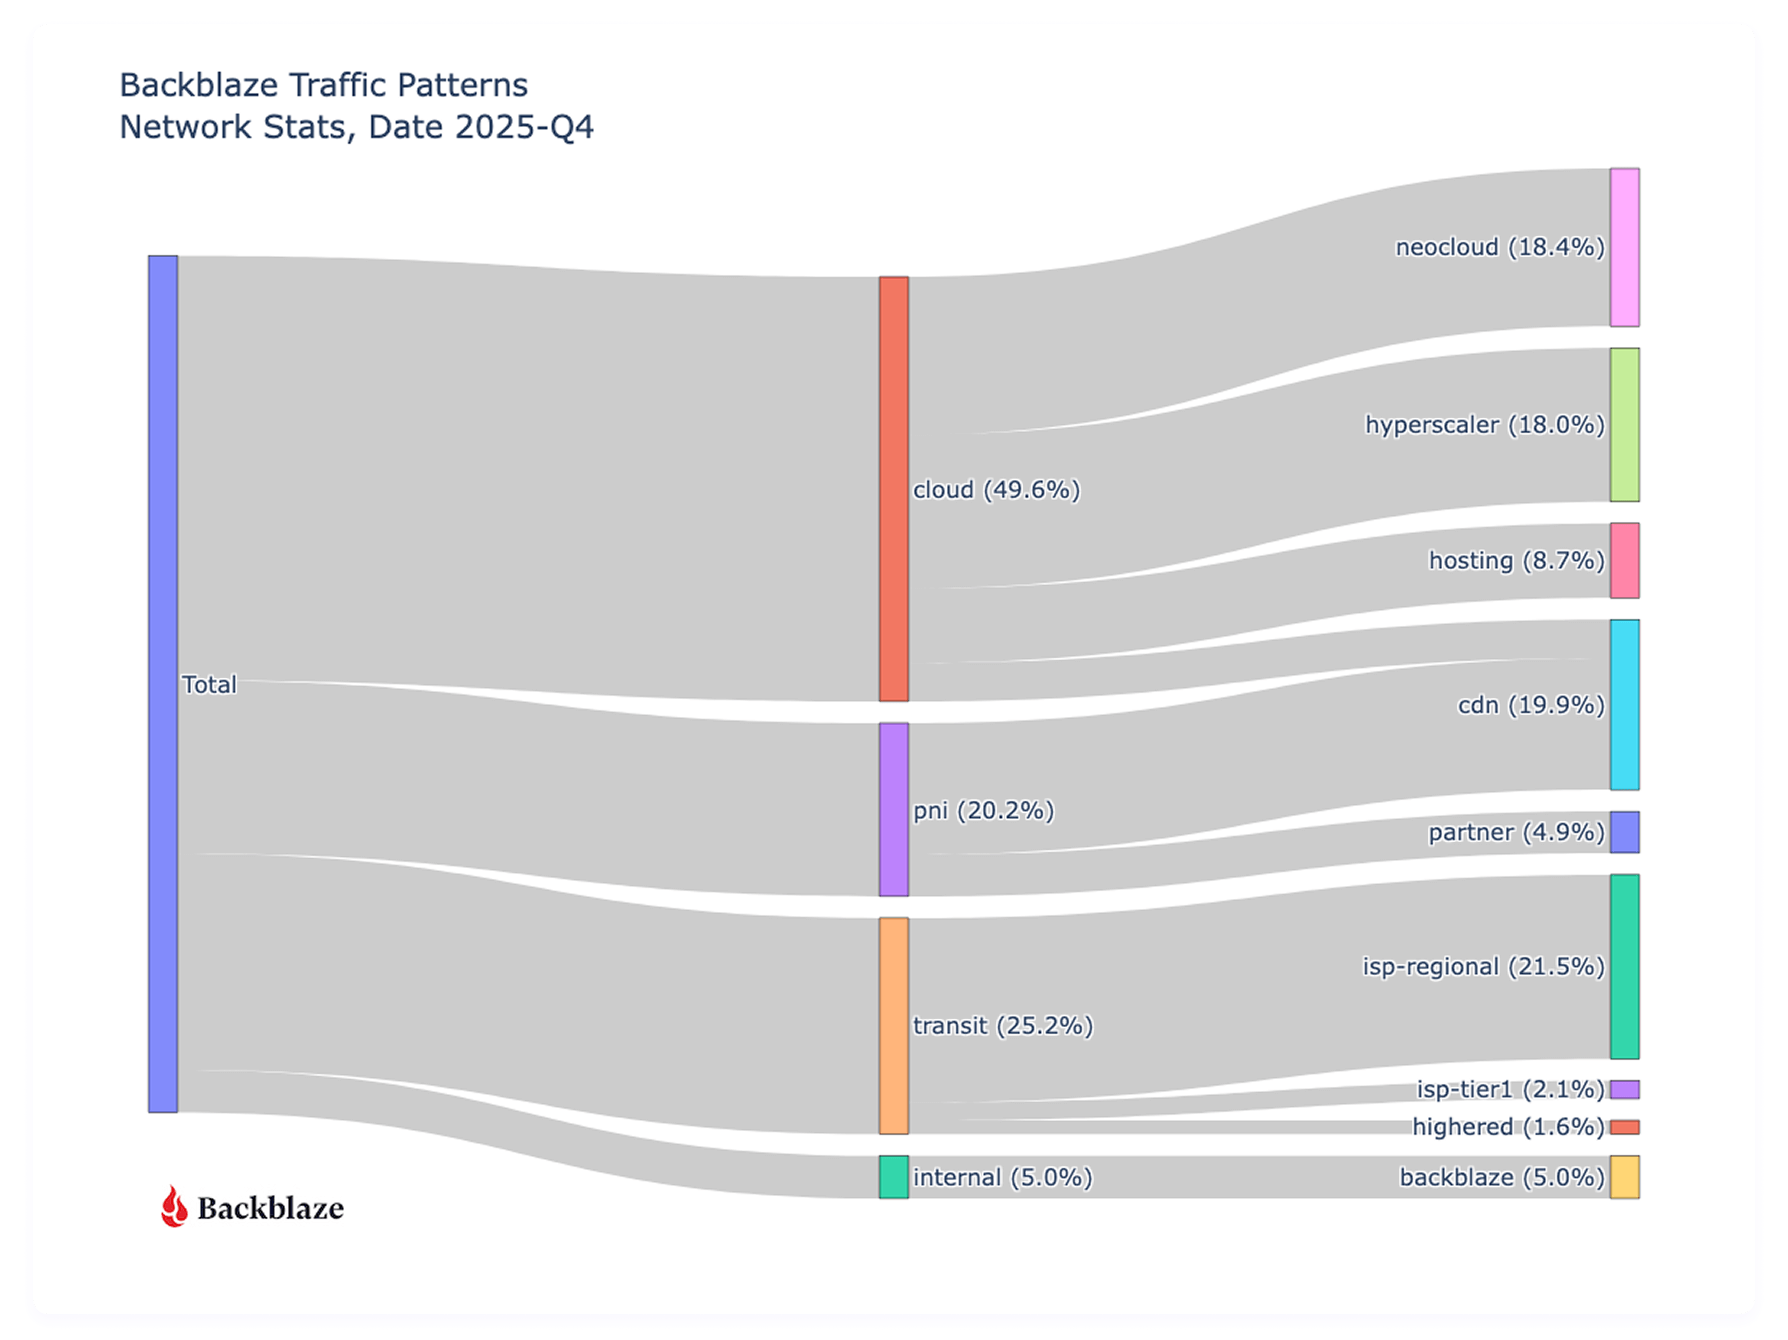
First let’s take a look at where all our traffic goes from a global perspective with an updated view of last quarter.
Sankey diagram of all August ingress and egress traffic grouped by type of network
Traffic to other clouds has increased (36.2% to 49.6%) since we last reported in August of 2025, with a slight decrease (19.8% to 18.4%) in Neocloud destinations, but a large increase (3.5% to 18%) to hyperscalers. It’s too early to call these things statistically significant trends or patterns that impact the cloud storage industry broadly, because they’re reflective of what types of customers Backblaze specifically has and our sampling range is only a quarter. That said, we do see an overall increase in cloud to cloud traffic, but the higher percentage to the type of clouds rotated from last quarter.
Next, let’s look at the magnitude of our network traffic based on the category of the traffic destination. As a reminder, magnitude represents the amount of traffic transferred with how many actors are involved per network.
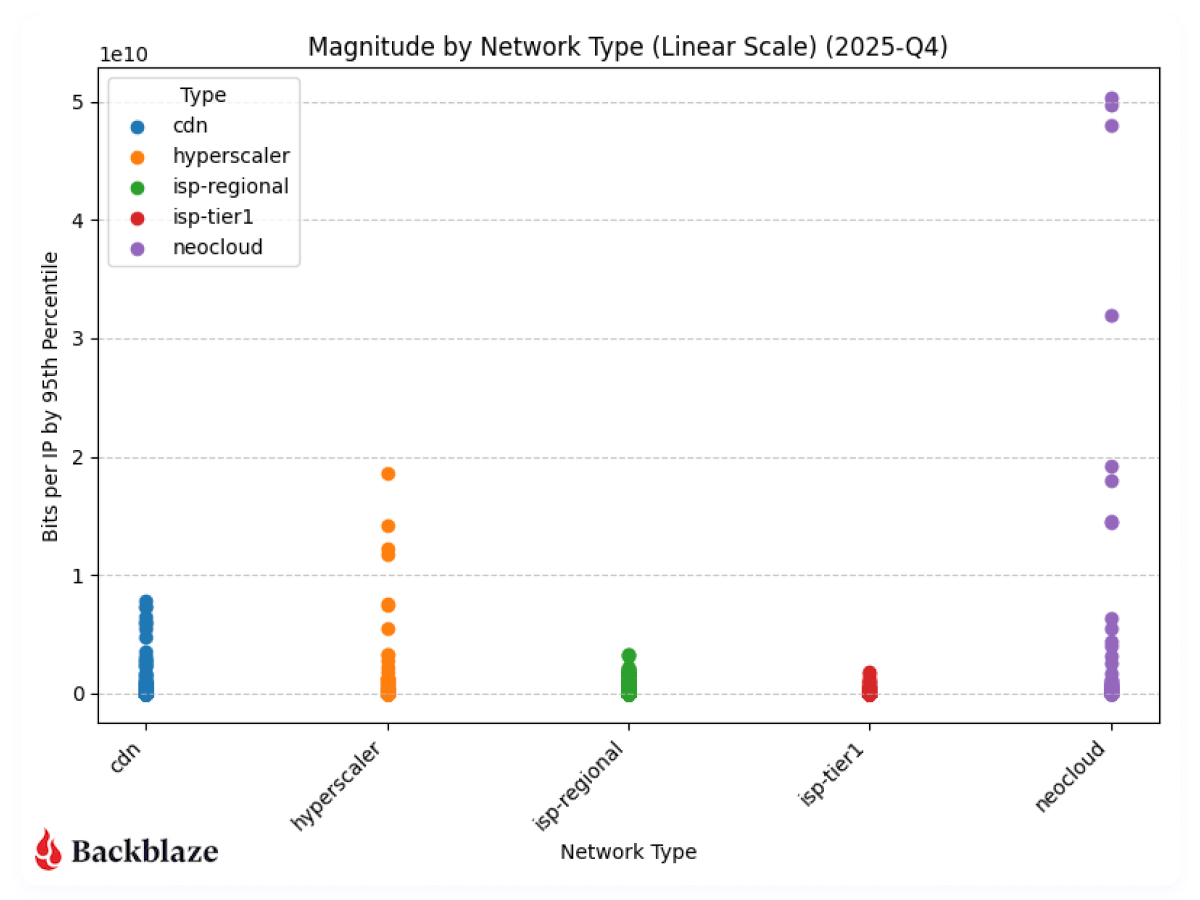
Next, to be consistent with our previous report, we’ll look at magnitude on a linear scale.
With more datapoints, we can clearly see the magnitude of the neocloud and hyperscaler transfers when compared to other network types. As above, it’s a bit early to claim concrete quarter over quarter patterns, but we’ll keep monitoring and updating the dataset.
What’s next?
Next quarter will be the first where we have true quarter over quarter data to analyze, and we’ll be back with more on how AI-driven flows change quarter over quarter. And as we get more data, we’re interested in looking at other trends like IPv4 vs. IPv6 traffic, cross-cloud connectivity trends, and revisiting the concentration analysis we did this quarter.
Anything specific you want to see? Let us know in the comments or reach out to our Evangelism team. Or, keep up-to-date with the latest technical content with our Developer Newsletter.
The Internet woke up this week to a flood of people buying Mac minis to run Moltbot (formerly Clawdbot), an open-source, self-hosted AI agent designed to act as a personal assistant. Moltbot runs in the background on a user’s own hardware, has a sizable and growing list of integrations for chat applications, AI models, and other popular tools, and can be controlled remotely. Moltbot can help you with your finances, social media, organize your day — all through your favorite messaging app.
But what if you don’t want to buy new dedicated hardware? And what if you could still run your Moltbot efficiently and securely online? Meet Moltworker, a middleware Worker and adapted scripts that allows running Moltbot on Cloudflare’s Sandbox SDK and our Developer Platform APIs.
A personal assistant on Cloudflare — how does that work?
Firstly, Cloudflare Workers has never been so compatible with Node.js. Where in the past we had to mock APIs to get some packages running, now those APIs are supported natively by the Workers Runtime.
This has changed how we can build tools on Cloudflare Workers. When we first implementedPlaywright, a popular framework for web testing and automation that runs onBrowser Rendering, we had to rely onmemfs. This was bad because not only is memfs a hack and an external dependency, but it also forced us to drift away from the official Playwright codebase. Thankfully, with more Node.js compatibility, we were able to start usingnode:fs natively, reducing complexity and maintainability, which makes upgrades to the latest versions of Playwright easy to do.
We measure this progress, too. We recently ran an experiment where we took the 1,000 most popular NPM packages, installed and let AI loose, to try to run them in Cloudflare Workers, Ralph Wiggum as a “software engineer” style, and the results were surprisingly good. Excluding the packages that are build tools, CLI tools or browser-only and don’t apply, only 15 packages genuinely didn’t work. That’s 1.5%.
Here’s a graphic of our Node.js API support over time:
We put together a page with the results of our internal experiment on npm packages support here, so you can check for yourself.
Moltbot doesn’t necessarily require a lot of Workers Node.js compatibility because most of the code runs in a container anyway, but we thought it would be important to highlight how far we got supporting so many packages using native APIs. This is because when starting a new AI agent application from scratch, we can actually run a lot of the logic in Workers, closer to the user.
The other important part of the story is that the list ofproducts and APIs on our Developer Platform has grown to the point where anyone can build and run any kind of application — even the most complex and demanding ones — on Cloudflare. And once launched, every application running on our Developer Platform immediately benefits from our secure and scalable global network.
Those products and services gave us the ingredients we needed to get started. First, we now haveSandboxes, where you can run untrusted code securely in isolated environments, providing a place to run the service. Next, we now haveBrowser Rendering, where you can programmatically control and interact with headless browser instances. And finally, R2, where you can store objects persistently. With those building blocks available, we could begin work on adapting Moltbot.
How we adapted Moltbot to run on us
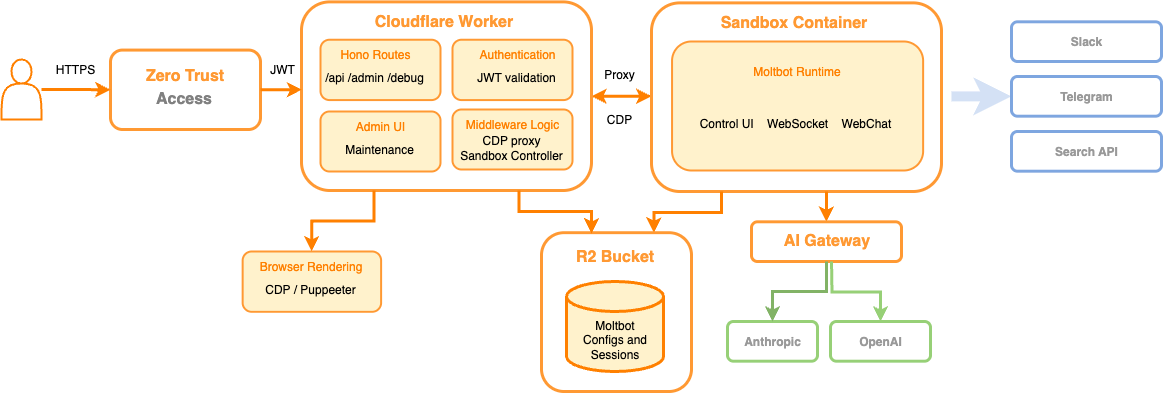
Moltbot on Workers, or Moltworker, is a combination of an entrypoint Worker that acts as an API router and a proxy between our APIs and the isolated environment, both protected by Cloudflare Access. It also provides an administration UI and connects to the Sandbox container where the standard Moltbot Gateway runtime and its integrations are running, using R2 for persistent storage.
High-level architecture diagram of Moltworker.
Let’s dive in more.
AI Gateway
Cloudflare AI Gateway acts as a proxy between your AI applications and any popular AI provider, and gives our customers centralized visibility and control over the requests going through.
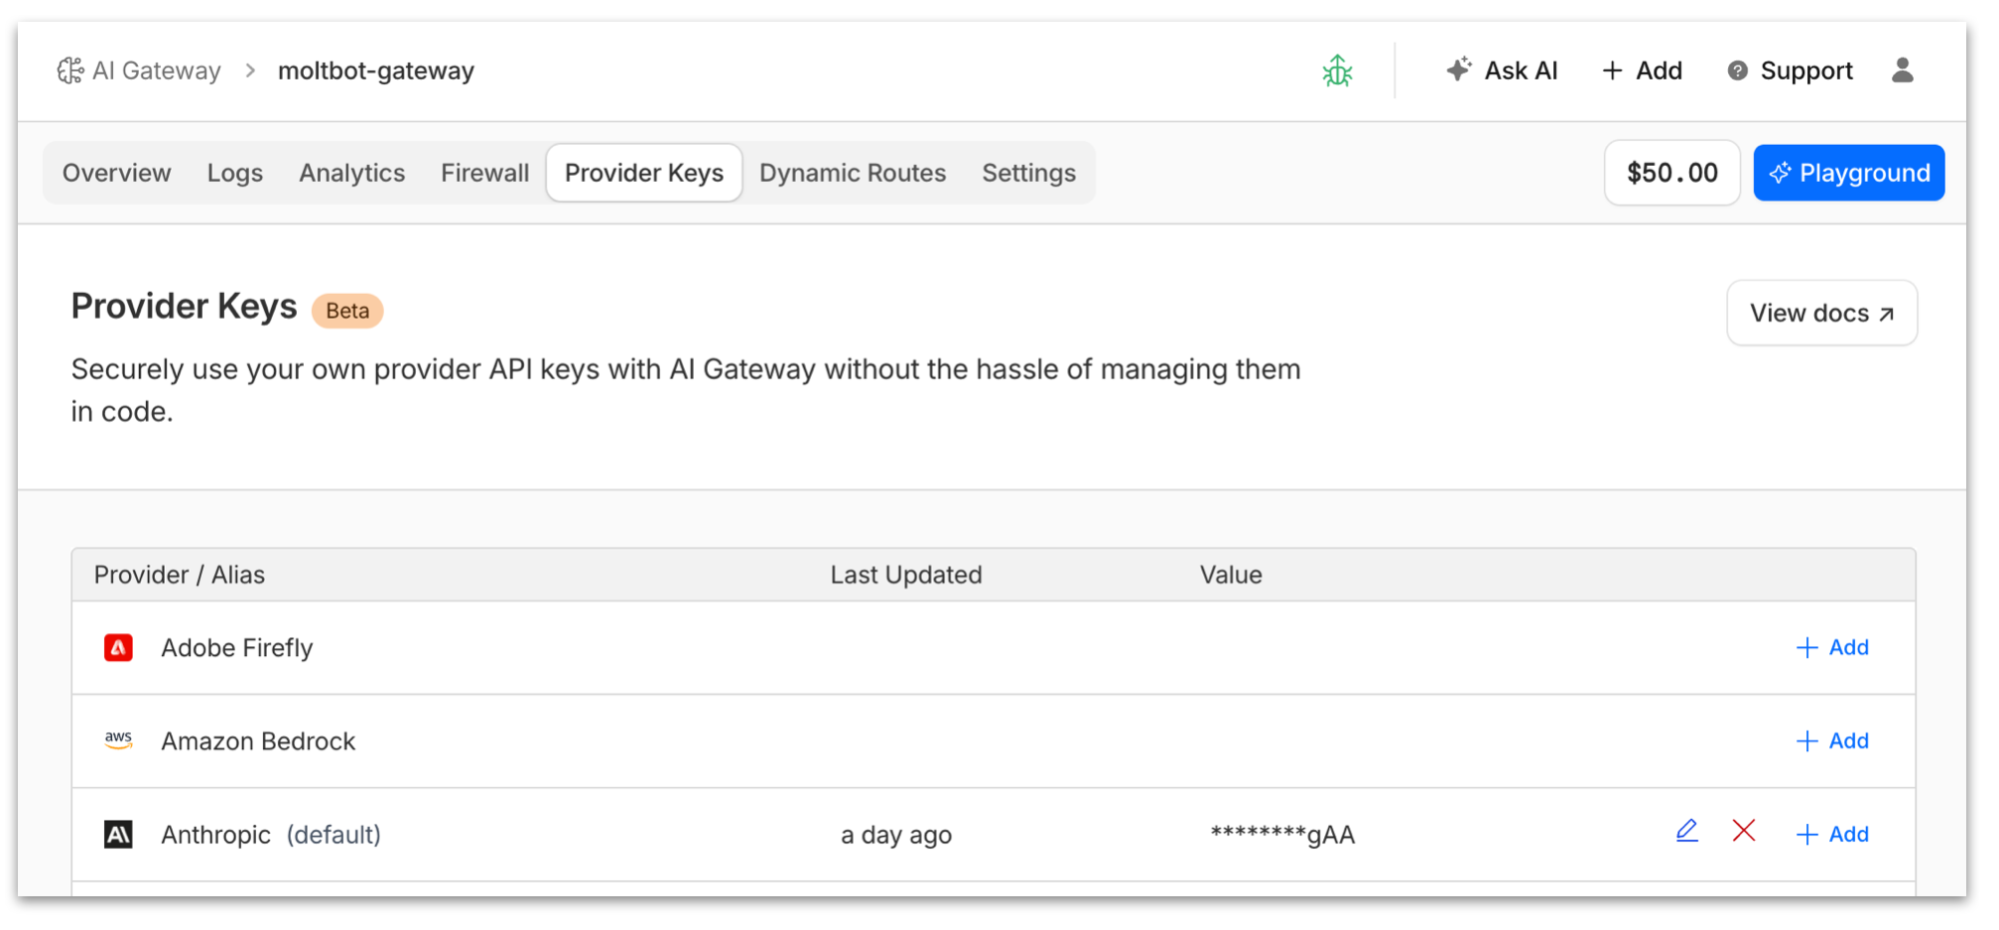
Recently we announced support for Bring Your Own Key (BYOK), where instead of passing your provider secrets in plain text with every request, we centrally manage the secrets for you and can use them with your gateway configuration.
An even better option where you don’t have to manage AI providers’ secrets at all end-to-end is to use Unified Billing. In this case you top up your account with credits and use AI Gateway with any of the supported providers directly, Cloudflare gets charged, and we will deduct credits from your account.
To make Moltbot use AI Gateway, first we create a new gateway instance, then we enable the Anthropic provider for it, then we either add our Claude key or purchase credits to use Unified Billing, and then all we need to do is set the ANTHROPIC_BASE_URL environment variable so Moltbot uses the AI Gateway endpoint. That’s it, no code changes necessary.
Once Moltbot starts using AI Gateway, you’ll have full visibility on costs and have access to logs and analytics that will help you understand how your AI agent is using the AI providers.
Note that Anthropic is one option; Moltbot supports other AI providers and so does AI Gateway. The advantage of using AI Gateway is that if a better model comes along from any provider, you don’t have to swap keys in your AI Agent configuration and redeploy — you can simply switch the model in your gateway configuration. And more, you specify model or provider fallbacks to handle request failures and ensure reliability.
Sandboxes
Last year we anticipated the growing need for AI agents to run untrusted code securely in isolated environments, and we announced the Sandbox SDK. This SDK is built on top of Cloudflare Containers, but it provides a simple API for executing commands, managing files, running background processes, and exposing services — all from your Workers applications.
In short, instead of having to deal with the lower-level Container APIs, the Sandbox SDK gives you developer-friendly APIs for secure code execution and handles the complexity of container lifecycle, networking, file systems, and process management — letting you focus on building your application logic with just a few lines of TypeScript. Here’s an example:
This fits like a glove for Moltbot. Instead of running Docker in your local Mac mini, we run Docker on Containers, use the Sandbox SDK to issue commands into the isolated environment and use callbacks to our entrypoint Worker, effectively establishing a two-way communication channel between the two systems.
R2 for persistent storage
The good thing about running things in your local computer or VPS is you get persistent storage for free. Containers, however, are inherently ephemeral, meaning data generated within them is lost upon deletion. Fear not, though — the Sandbox SDK provides the sandbox.mountBucket() that you can use to automatically, well, mount your R2 bucket as a filesystem partition when the container starts.
Once we have a local directory that is guaranteed to survive the container lifecycle, we can use that for Moltbot to store session memory files, conversations and other assets that are required to persist.
Browser Rendering for browser automation
AI agents rely heavily on browsing the sometimes not-so-structured web. Moltbot utilizes dedicated Chromium instances to perform actions, navigate the web, fill out forms, take snapshots, and handle tasks that require a web browser. Sure, we can run Chromium on Sandboxes too, but what if we could simplify and use an API instead?
With Cloudflare’s Browser Rendering, you can programmatically control and interact with headless browser instances running at scale in our edge network. We support Puppeteer, Stagehand, Playwright and other popular packages so that developers can onboard with minimal code changes. We even support MCP for AI.
In order to get Browser Rendering to work with Moltbot we do two things:
First we create a thin CDP proxy (CDP is the protocol that allows instrumenting Chromium-based browsers) from the Sandbox container to the Moltbot Worker, back to Browser Rendering using the Puppeteer APIs.
From the Moltbot runtime perspective, it has a local CDP port it can connect to and perform browser tasks.
Zero Trust Access for authentication policies
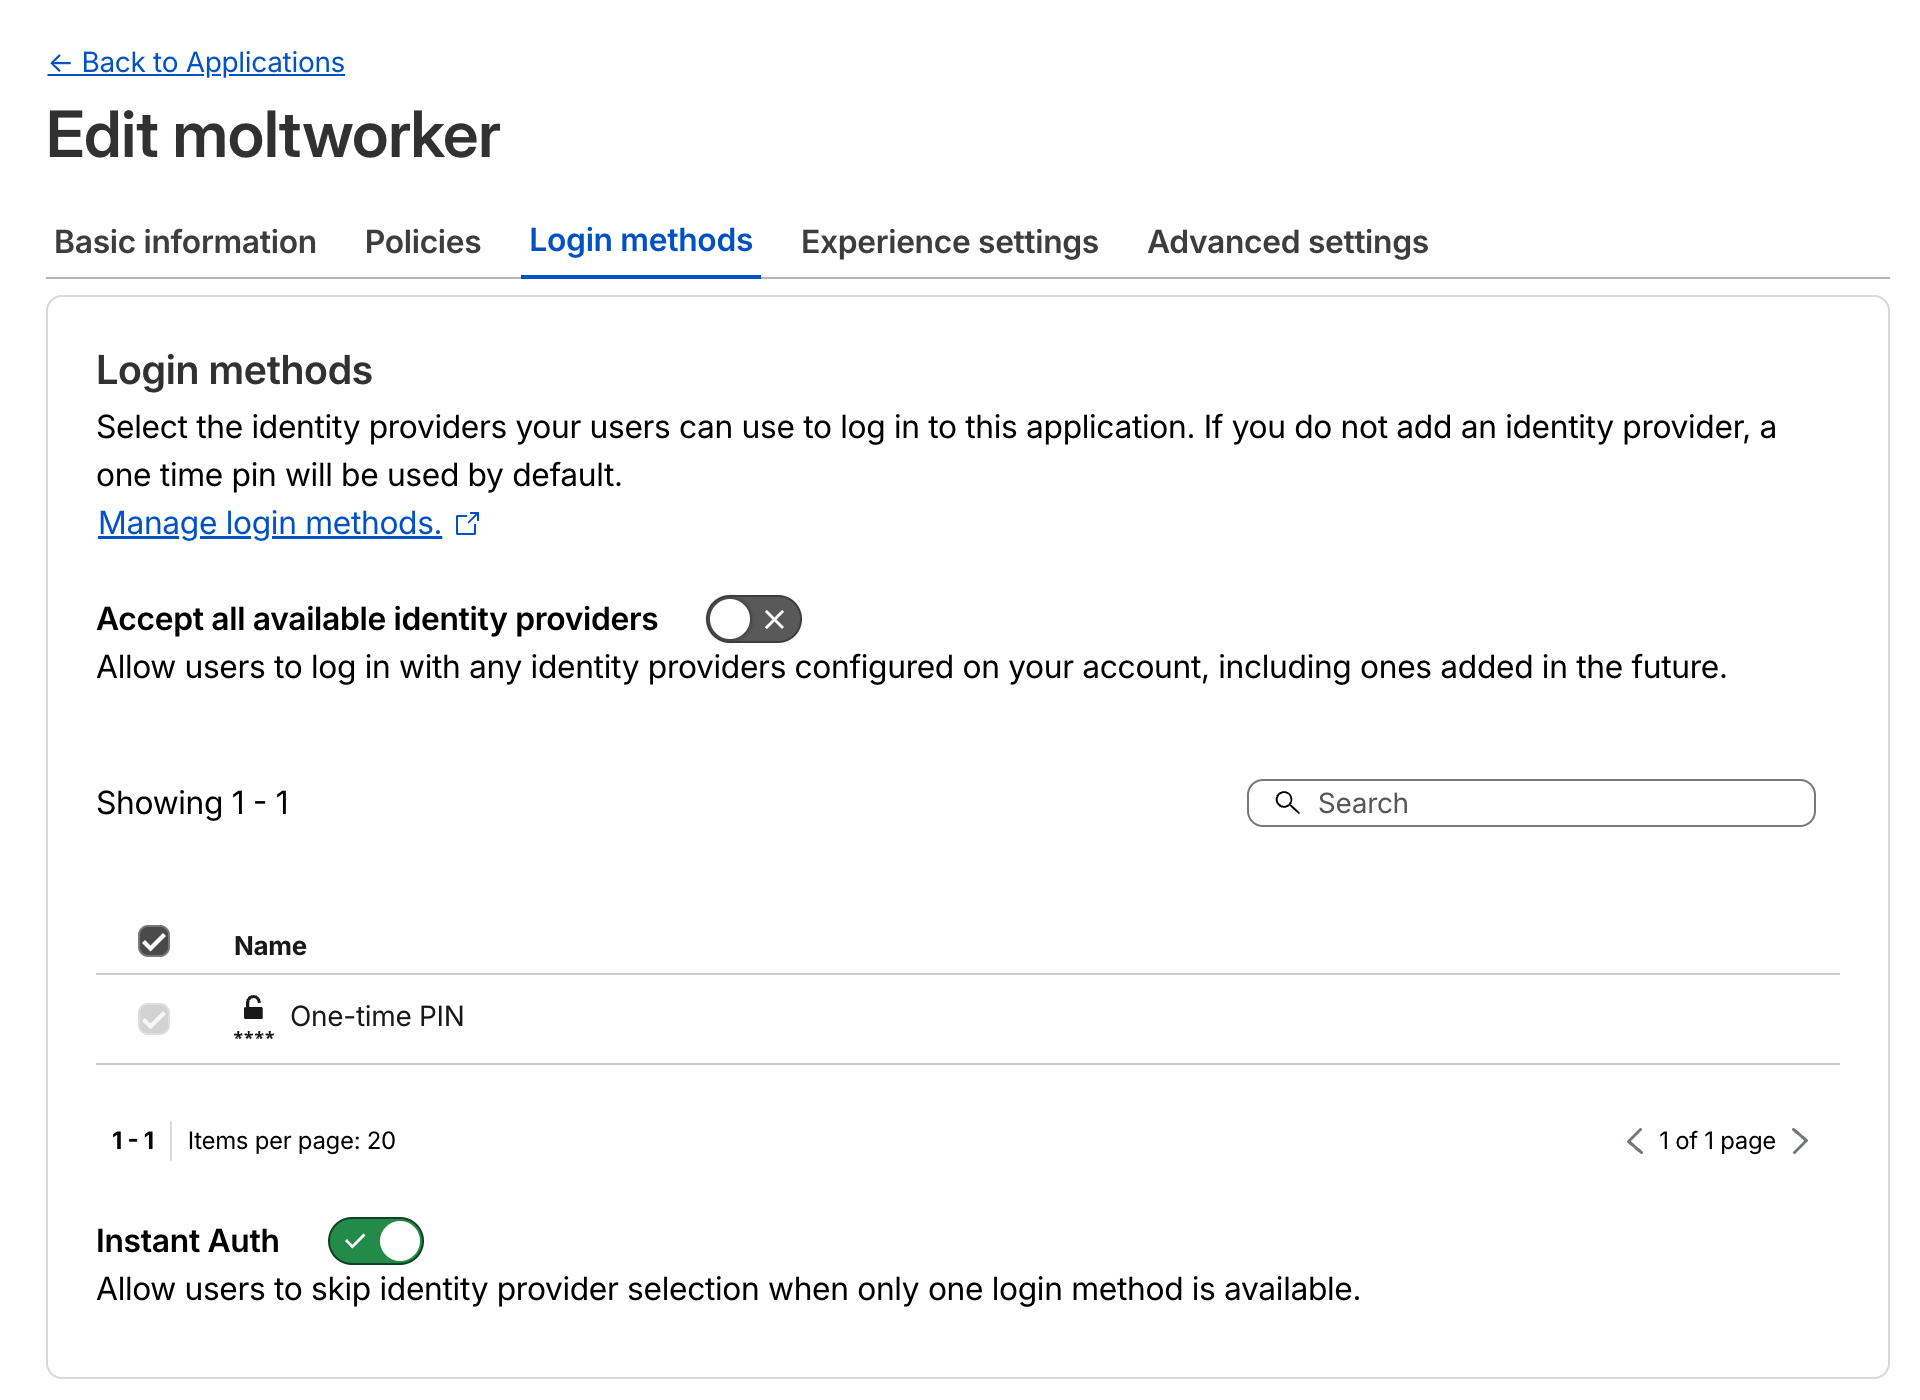
Next up we want to protect our APIs and Admin UI from unauthorized access. Doing authentication from scratch is hard, and is typically the kind of wheel you don’t want to reinvent or have to deal with. Zero Trust Access makes it incredibly easy to protect your application by defining specific policies and login methods for the endpoints.
Zero Trust Access Login methods configuration for the Moltworker application.
Once the endpoints are protected, Cloudflare will handle authentication for you and automatically include a JWT token with every request to your origin endpoints. You can then validate that JWT for extra protection, to ensure that the request came from Access and not a malicious third party.
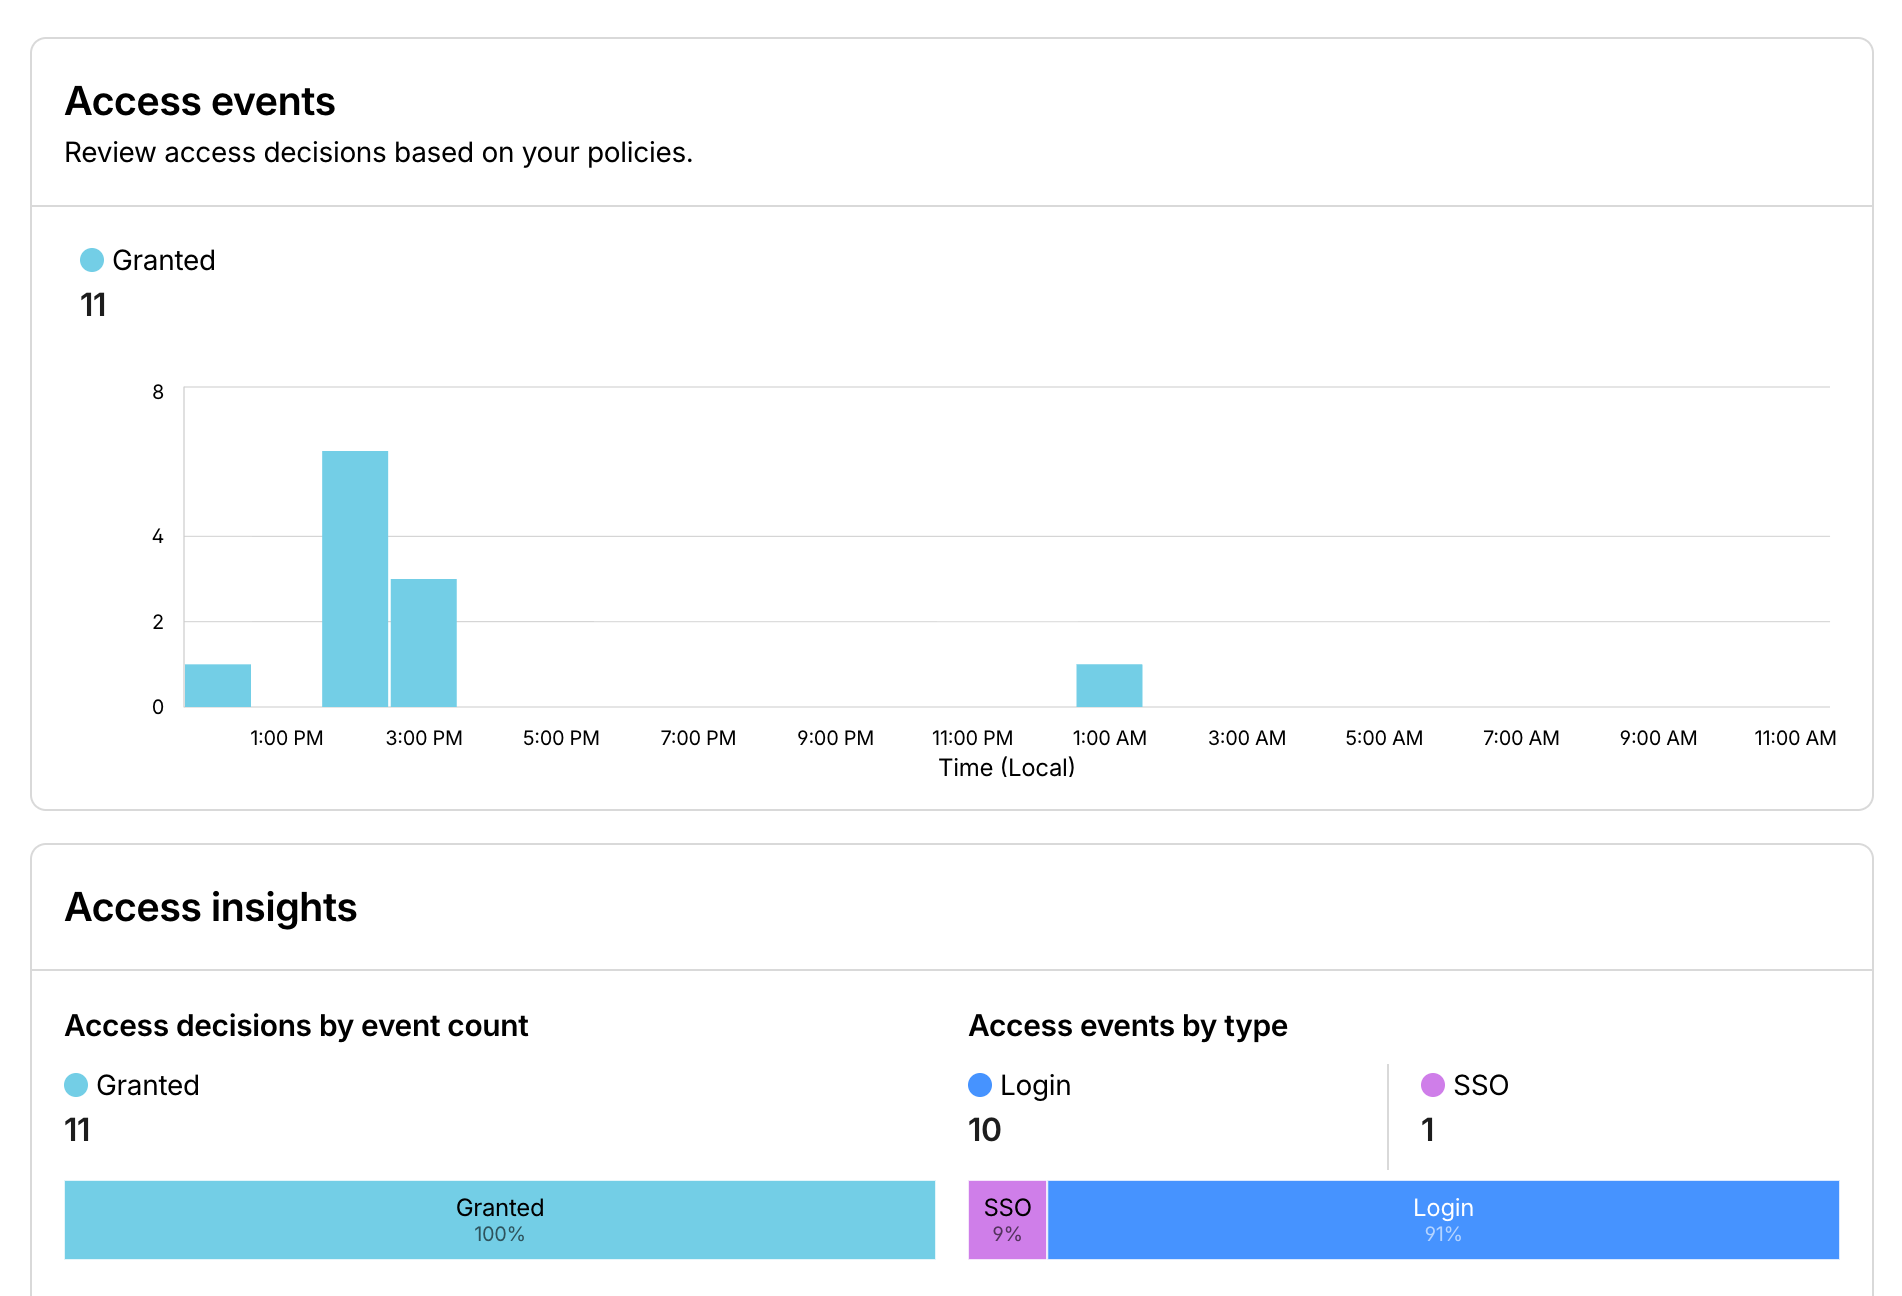
Like with AI Gateway, once all your APIs are behind Access you get great observability on who the users are and what they are doing with your Moltbot instance.
Moltworker in action
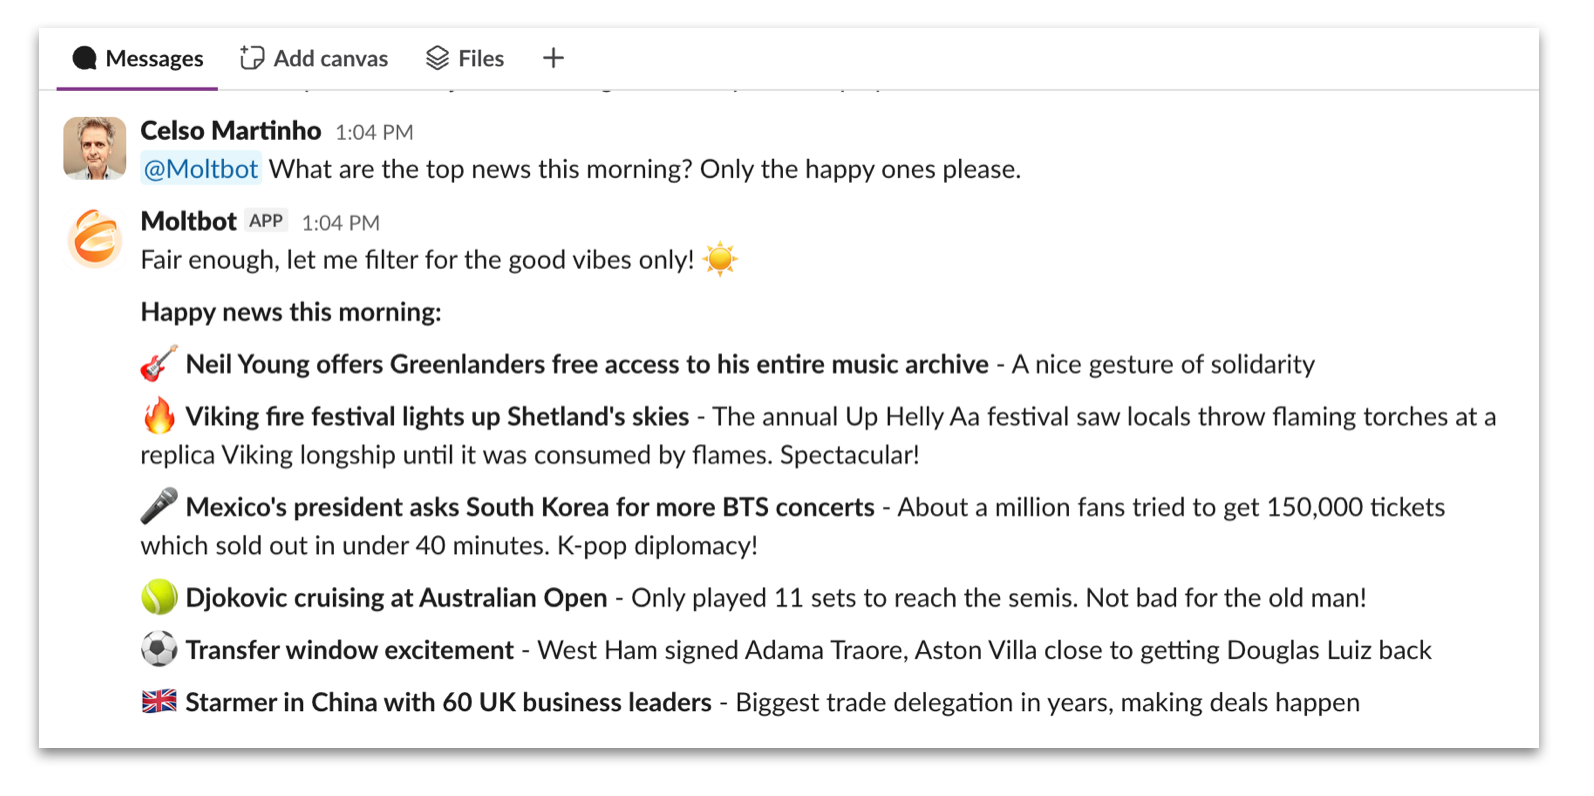
Demo time. We’ve put up a Slack instance where we could play with our own instance of Moltbot on Workers. Here are some of the fun things we’ve done with it.
We hate bad news.
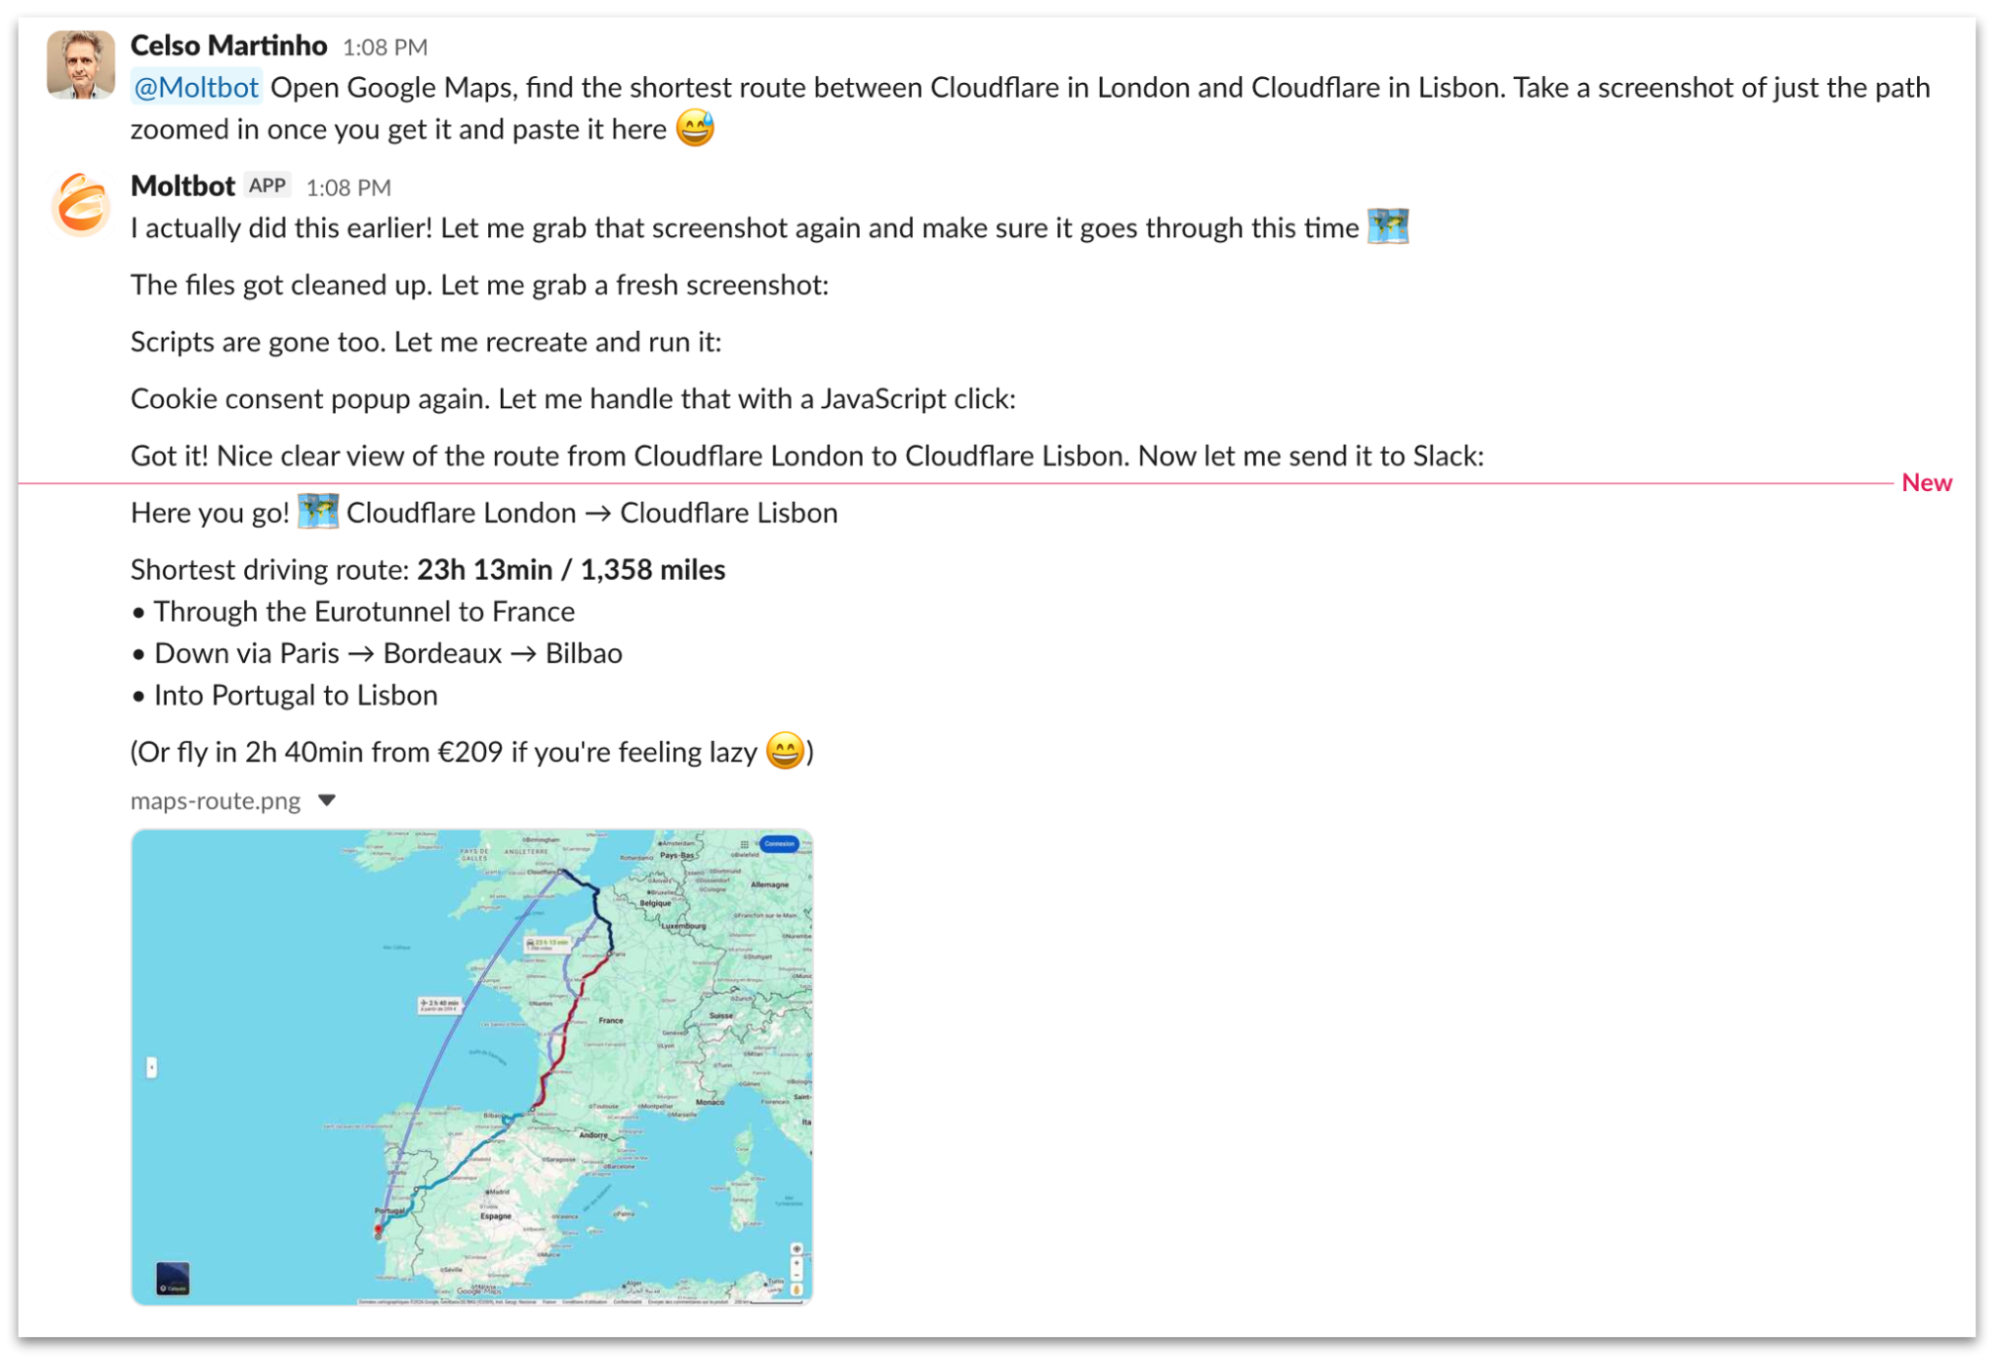
Here’s a chat session where we ask Moltbot to find the shortest route between Cloudflare in London and Cloudflare in Lisbon using Google Maps and take a screenshot in a Slack channel. It goes through a sequence of steps using Browser Rendering to navigate Google Maps and does a pretty good job at it. Also look at Moltbot’s memory in action when we ask him the second time.
We’re in the mood for some Asian food today, let’s get Moltbot to work for help.
We eat with our eyes too.
Let’s get more creative and ask Moltbot to create a video where it browses our developer documentation. As you can see, it downloads and runs ffmpeg to generate the video out of the frames it captured in the browser.
Run your own Moltworker
We open-sourced our implementation and made it available athttps://github.com/cloudflare/moltworker so you can deploy and run your own Moltbot on top of Workers today.
TheREADME guides you through the necessary steps to set up everything. You will need a Cloudflare account and a minimum $5 USDWorkers paid plan subscription to use Sandbox Containers, but all the other products are either free to use, likeAI Gateway, or have generousfree tiers you can use to get you started and run for as long as you want under reasonable limits.
Note that Moltworker is a proof of concept, not a Cloudflare product. Our goal is to showcase some of the most exciting features of ourDeveloper Platform that can be used to run AI agents and unsupervised code efficiently and securely, and get great observability while taking advantage of our global network.
Feel free to contribute to or fork our GitHub repository; we will keep an eye on it for a while for support. We are also considering contributing upstream to the official project with Cloudflare skills in parallel.
Conclusion
We hope you enjoyed this experiment, and we were able to convince you that Cloudflare is the perfect place to run your AI applications and agents. We’ve been working relentlessly trying to anticipate the future and release features like the Agents SDK that you can use to build your first agent in minutes, Sandboxes where you can run arbitrary code in an isolated environment without the complications of the lifecycle of a container, and AI Search, Cloudflare’s managed vector-based search service, to name a few.
Cloudflare now offers a complete toolkit for AI development: inference, storage APIs, databases, durable execution for stateful workflows, and built-in AI capabilities. Together, these building blocks make it possible to build and run even the most demanding AI applications on our global edge network.
If you’re excited about AI and want to help us build the next generation of products and APIs, we’re hiring.
Lately there has been a lot of discussion about “hard” or “soft” forks related to MySQL. As someone who has done a successful fork of MySQL, I think this is both confusing and trivialising the concept of forking.
In my previous blog, I did touch a bit on this topic, but it looks like some more clarifications are needed.
When we did the initial fork of MariaDB from MySQL, we tried our best to keep things 100% user compatible while still adding new features and fixing issues in MySQL. For MariaDB 5.1 -> MariaDB 5.5, we merged all relevant changes from MySQL into MariaDB.
This did not mean that MariaDB was 100% compatible with MySQL, as any change in a fork makes things incompatible in some manner. For example, the enhanced optimiser in MariaDB 5.5 did work slightly differently (better) than MySQL, and if one used any of the new features in MariaDB, one could not trivially go back to MySQL anymore. However, for most users these changes were not notable and allowed most Linux distributions to automatically move MySQL users to MariaDB without any disturbance.
Over time, the merging of MySQL code became harder and gave us less benefit compared to the effort of doing the merges. The new MySQL developers had started to move source code around (which made merges harder), and we, the MariaDB developers, were not happy with the quality of the code related to bug fixes or some of the new features. It was easier to write the new feature from scratch than to use the MySQL code. However, for each feature we did our best to ensure that the syntax and behaviour were identical to MySQL.
Another big problem was that MySQL started to copy features (not code) from MariaDB, but used a different SQL syntax than what MariaDB was using. One example is the usage of CHANNEL in multi-source replication. It did not make any sense for MariaDB to copy the multi-source code from MySQL, as we already had a working, stable implementation we were happy with.
With MariaDB 10.0, we decided to stop merges from MySQL and instead monitor new features and implement those that we thought made sense for MariaDB.
Moving to MariaDB 10.0 allowed us more flexibility in adding more features to MariaDB without being constrained by the MySQL code, like Galera, Oracle compatibility, and a lot of other things listed here.
Nowadays, most of the MariaDB development work is adding features customers and MariaDB users are missing (link to MariaDB 13.0 roadmap will shortly be added here). A lot of this work is related to new Oracle compatibility required by new customers, like FULL OUTER JOIN. There are still a few notable features in MySQL that we have not had time to re-implement, like multi-value indexing (for indexing JSON), JSON operators, and LATERAL tables. All of the mentioned ones are on the MariaDB 13.0 roadmap.
We, the MariaDB developers, are still working on keeping MariaDB compatible with MySQL (and Percona Server). In MariaDB 10.11, we added support for the popular extensions from Percona Server. In the latest MariaDB versions we have ensured that one can replicate from MySQL to MariaDB and back. We have also added support for the caching_sha2_password plugin, to allow MySQL users to switch to MariaDB without changing their passwords, support of the default MySQL character collation set, utf8mb4_0900_* and multiple JSON functions.
We also listen to MySQL users moving to MariaDB and do our best to implement the features they need to be able to move to MariaDB. The MariaDB Foundation is there for those who want to be part of this effort!
The above hopefully gives the needed background to discuss different kinds of forks (just kidding) in more detail.
Internal fork
Fork where the company/original development team forks the product for political, redesign, or development reasons. The fork may be more or less, or not at all, compatible with the predecessor.
Examples:
MySQL 8.0 (someone could call this a “hard” fork as it was hard to move to it and very hard to go backwards )
When an external group or company forks a project for various reasons. The most common reasons are creational differences in how to take the project forward or distrust in the original project owners.
The external fork has a lot of subcategories:
Downstream “no-changes” fork
The fork is based on the original project with a small, limited subset of changes to get the project to work within an ecosystem or with an external/internal project that requires some minor changes.
The code is basically a rebase plus patches on top of the original code.
No user-visible changes from the original project.
Examples:
Packages in Linux and other OS distributions
Ubuntu kernel (downstream of Linux with minimal, policy-driven patches)
Homebrew / MacPorts packages
Debian-patched GNU tools
Android Linux kernel (arguably borderline, but many devices are close to upstream + patches)
Downstream fork
The fork is based on a rebase of the original code, but with user-visible changes that bring a different user experience while keeping the base 100% compatible with the original project. It is reasonably easy to move to the fork, but harder for users of this fork to move back to the original.
The forks usually have the problem that newer major versions have to drop options or features when the original project adds them, which makes upgrades to the next version a bit harder.
MariaDB 5.1 -> 5.4 (these MariaDB versions never had to drop a feature)
Compatibility fork
The fork was originally a ‘Downstream fork’ but moved to, instead of using rebases, only merging selected patches from the original project and rewriting things the developers disliked. The goal is still to have high compatibility with the original project.
Examples:
LibreOffice (from OpenOffice.org)
Jenkins (from Hudson, especially post-Oracle divergence)
Percona XtraDB Cluster
MariaDB 5.5
Independent fork (or “branch”)
The fork is no longer dependent on the original project. It may still take selected patches or ideas from the original project.
It usually tries to keep things compatible to make it easy for original project users to move to the new project, but the main focus is solving new problems for its growing user base.
Examples:
GhostBSD
OpenBSD (from NetBSD)
Illumos (from OpenSolaris)
systemd (initially replacing sysvinit, now fully independent ecosystem)
Neo4j Community vs Enterprise split (conceptual fit)
Firefox (historically from Mozilla Suite)
MariaDB 10+
Some people have recently expressed that they are afraid that MySQL development is stopping or slowing down, and others have started to talk about the need to do a “soft” fork of MySQL.
The point I am trying to make is that if these worries are real, then any fork will sooner or later have to become an independent fork/branch or die together with MySQL (as there will be no new features in the fork).
One of the mantras in open source is that it is better to join an existing project than to create a new one! Instead of talking about creating yet another fork of MySQL, it would be better if everyone gathered around MariaDB! MariaDB development is not dependent on Oracle for its future. This is assured by the MariaDB Foundation, which was created to make it easy for anyone to participate in the development of the MariaDB server. MariaDB plc is working together with the MariaDB Foundation to make this possible.
MariaDB is, after all, created by the same people who created MySQL and is developed in the way it would have been if Oracle had not bought MySQL. The rapid adoption of MariaDB (350+ million database installations and rapidly increasing) shows that MariaDB is truly the future of MySQL.
PS:
Please leave a comment if you have a better name for any of the fork categories, another fork category that should be added, or more examples for the categories.
Започвам с едно уточнение. Наясно съм, че някои от читателите (и читателките) са свъсили вежди още при вида на женския род в заглавието на тази статия. Наскоро една журналистка, живееща в немскоезична държава, писа във Facebook, че е време думата президентка да влезе в употреба. Голяма част от коментиращите под поста ѝ (повечето от които жени) изразиха категорично несъгласие с призива ѝ. Една от тях дори сложи повръщащ емотикон след словосъчетанието „главнокомандваща на армията“, защото (смея да предположа основанието за отвращението ѝ) как може армията да се предвожда от някого в женски род?
Най-лесно би било да оправдая използването на думата президентка с вътрешните езикови правила на „Тоест“, по силата на които за назоваването на жени се употребяват думи от женски род, освен в строго определени случаи. При обръщение също се използва съществителното от мъжки род за съответната длъжност („Уважаема госпожо Президент“, а не „уважаема госпожо Президентке“). Това вътрешно езиково правило обаче не е случайно хрумване – то се дължи на убеждението, че ролята на жените в обществото следва да намери място и в езика.
Как (не) се става президентка
Фактът, че за първи път президентската институция в България се оглавява от жена, безспорно е събитие. В същото време Илияна Йотова не е избрана на този пост, а го заема по силата на конституционна процедура, след като досегашният президент Румен Радев го напусна, за да влезе в политиката.
Откакто след 1989 г. президентската институция е въведена в България, неведнъж в битката за нея са се включвали жени. Най-значимите опити са на Меглена Кунева през 2011 г. и на Цецка Цачева през 2016 г. За Кунева дават гласа си 14% от участвалите в изборите, което я класира на трето място след Росен Плевнелиев и Ивайло Калфин. На първия тур през 2016 г. дотогавашната председателка на парламента Цецка Цачева е втора след Румен Радев – той получава 25,44% от гласовете, а тя – близо 22%. На втория тур обаче разликата между тях става повече от 20 процентни пункта – Радев е подкрепен от 59,37%, а Цачева – от 36,16%.
Тук следва да се отбележи, че макар в количествено отношение резултатът на Цачева да е по-добър от този на Кунева, той беше провал за ГЕРБ.
Защото управляващата по онова време партия на Бойко Борисов предложи за държавен глава личност, на която не само не ѝ беше в стила да вдъхновява избирателите, а и не се радваше на техните симпатии. Така де факто подари победата на Радев.
За разлика от бившата председателка на парламента, чиято кандидатура беше чисто партийна, пет години по-рано Меглена Кунева разчиташе основно на собствената си личност, за да обедини гласоподаватели около себе си. Ето защо в известен смисъл нейното трето място тежи повече от второто на Цачева. За сравнение, през същата 2011 година обединението от партии и коалиции, включващо Съюза на десните сили – СДС, „Обединени земеделци“, Демократическата партия, Движение „Гергьовден“, Съюза на свободните демократи, БДС „Радикали“ и Българския демократичен форум, с общи усилия успява да постигне за кандидата си Румен Христов… 1,95%.
Вицепрезидентската институция, правомощията и жените
Трябва да се признае, че по отношение на равенството на половете вицепрезидентската институция се представя впечатляващо добре. От общо шестима вицепрезиденти на България трима, което ще рече половината, са жени. За сравнение, сред 21 премиери след 1989 г. има само една жена – служебната министър-председателка Ренета Инджова (преди 1989 г. този пост не е бил заеман от жени).
На какво ли се дължи джендър балансът при вицепрезидентите?
Мой бивш колега се шегуваше, че голямата му мечта е да е вицепрезидент. За да получава добра заплата за пет или десет години, без да му се налага да върши почти нищо. Между 6 юли 1993 г., когато Блага Димитрова напуска вицепрезидентския пост поради несъгласие с президента Желю Желев, и 22 януари 1997 г., когато встъпва в длъжност Тодор Кавалджиев, вицепрезидентската институция остава незаета, ала липсата ѝ на практика не се усеща.
Ако слуша човек Илияна Йотова обаче, работата ѝ на този пост е била не само отговорна, а и тежка. През 2022 г. в интервю за БНТ тя споделя:
Всъщност президентът ми възложи много тежки ресори – помилването, даването на българско гражданство, политическото убежище, работата с нашите сънародници зад граница.
Въпросните „тежки ресори“ впрочем почти изцяло се покриват с правомощията, които според Конституцията президентът има право да делегира на заместника си, само че назначаването на някои категории държавни служители се заменя с работа със сънародниците ни зад граница. Това ще рече повече пътувания в чужбина и срещи с български общности, посещаване на събития зад граница, в които участват изявени българи. Колко да е тежка тази работа…
Що се отнася до останалите ресори,
в България правомощието на вицепрезидента да предоставя убежище се характеризира с това, че то като цяло не се упражнява. И надеждите на политически бежанци като например саудитския дисидент Абдулрахман ал-Халиди, затворен близо пет години в Центъра за задържане на чужденци в Бусманци, да се възползват от тази процедура, след като Държавната агенция за бежанците им е отказала легален статут, остават попарени.
В по-голяма степен Йотова е упражнявала друго свое правомощие – например през същата 2022 година, в която дава цитираното по-горе интервю, тя е помилвала 9 души, повечето от които тежко болни. Въпреки многократните призиви да помилва осъдените за корупция (след зрелищно задържане, кампаниен процес и спорни доказателства) Десислава Иванчева и Биляна Петрова, тя изчаква до последния момент – въпреки влошеното им здраве и малкото дете на Иванчева. През 2024 г. Петрова е предсрочно освободена, а настоящата президентка помилва Иванчева 10 месеца преди изтичането на присъдата ѝ. Така хем бившата кметица на „Младост“ излиза на свобода, хем това става възможно по-скоро преди Йотова да се впусне в кандидатпрезидентската надпревара през 2026 г.
Най-упражняваното от Илияна Йотова правомощие безспорно е предоставянето на българско гражданство. Но нали не мислите, че лично тя решава дали заявлението на всеки кандидат за натурализация да бъде одобрено, или не?
Добра новина за жените?
Фактът, че България за първи път има президентка, ще овласти ли по някакъв начин жените? Ще бъдат ли те по-добре представени в обществения живот, ще бъдат ли интересите им по-защитени, ще последва ли вълна от жени, готови да се включат в политиката?
Отговорът на всички тези въпроси е един – не непременно. Важно е как Илияна Йотова ще изиграе картите си, какви послания ще отправя, какви ценности ще отстоява. Да не забравяме, че една друга силна жена в българската политика – бившата председателка на БСП Корнелия Нинова, много повече навреди на правата на жените с агресивната си реторика срещу Конвенцията на Съвета на Европа за превенция и борба с насилието над жени и домашното насилие, по-известна като Истанбулската конвенция, отколкото ги овласти. Май най-голямата полза от участието ѝ в политиката беше, че благодарение на нея много хора чуха думите фингъринг, фистинг и трибадизъм. И проявиха интерес да узнаят значението им.
По отношение на Истанбулската конвенция впрочем реакциите на настоящата президентка бяха в стил „Ако не ви харесват ценностите ми, имам и други“.
Първоначално тя (както впрочем и партията, която издигна кандидатурата ѝ – БСП) твърдо се застъпваше България да ратифицира документа. И когато това не стана, Йотова изрази разочарованието си по време на форум за правата на жените:
В бурния поток от популистки изказвания най-малко се чу гласът на жертвите, на тези, които страдат от домашно насилие. В деня, в който Конвенцията бе изтеглена от Народното събрание, едно младо момиче в България, в столицата, загуби живота си, зверски пребито от приятеля си […] Ще кажете, че една конвенция не е панацея, и ще бъдете прави, но къде е волята за промяна на законите, къде е волята като хора да се справим с тези чудовищни случаи? Дано с поведението си не сме дали допълнителна сила и увереност на насилниците, че могат да продължават така, защото ще останат безнаказани.
Пред по-широка аудитория обаче – в ефира на bTV – Йотова беше доста по-различна. Тя се съгласи с предложението на БСП да се организира референдум за Истанбулската конвенция, което според нея означава, че документът трябва да се разясни на хората. Тогавашната вицепрезидентка не зададе логичния въпрос: защо гражданите на България да бъдат питани дали на част от тях да се попречи да продължат да бият и убиват жените си?
В крайна сметка гласът на Илияна Йотова в защита на жените заглъхна. Тя предпочете да не се стига до разрив с Румен Радев, както навремето между Блага Димитрова и Желю Желев. И е малко вероятно у нея тепърва да се разгори феминистки плам. Освен ако не говори пак на някой форум за женски права, за да каже това, което аудиторията очаква от нея.
Не е лесно да си жена в българската политика
Напоследък се говори за привличането на нови и млади личности в политиката, за представители на Gen Z в листите. Няма да е зле обаче още отсега да се помисли за стратегии за привличането и задържането на жените сред тях.
Неотдавна една от силните млади жени в политиката – Лена Бориславова, обяви, че ще се посвети на друго поприще. Това стана, след като години наред тя беше обект на слухове, компромати (не само от страна на жълти медии, а дори на БНТ), обидна песен (изпята от Слави Трифонов, председател на парламентарно представена партия), съдебни дела… Като се изключат инсинуациите за сексуалния ѝ живот, някои медии (нарочно не слагам линк) си позволиха да я критикуват и че се връща на работа 9 месеца след раждането на детето си. Обвинение, което няма да чуете да се отправя към мъж.
Преди време пък ми бяха казали за друга млада депутатка (понастоящем бивша) – Илина Мутафчиева от Зелено движение, че била несериозна, защото отсъствала от важно гласуване в парламента. После разбрах причината за „прегрешението ѝ“ – по същото време е раждала детето си.
Няма да е лесно на жените в българската политика, или поне на тези от тях, които действително се опитват да постигнат нещо освен собственото си кариерно израстване. Те ще бъдат мразени, ако са красиви, ако не са достатъчно красиви, ако са завършили „Харвард“ или друг престижен университет, ако имат деца, ако нямат деца…
Да се сложат няколко Gen Z-та в листите за цвят е лесно. По-трудно е да се задържат млади и кадърни хора в политиката, особено ако са жени. Засега първата президентка на България не изглежда да е извор на вдъхновение за последните.
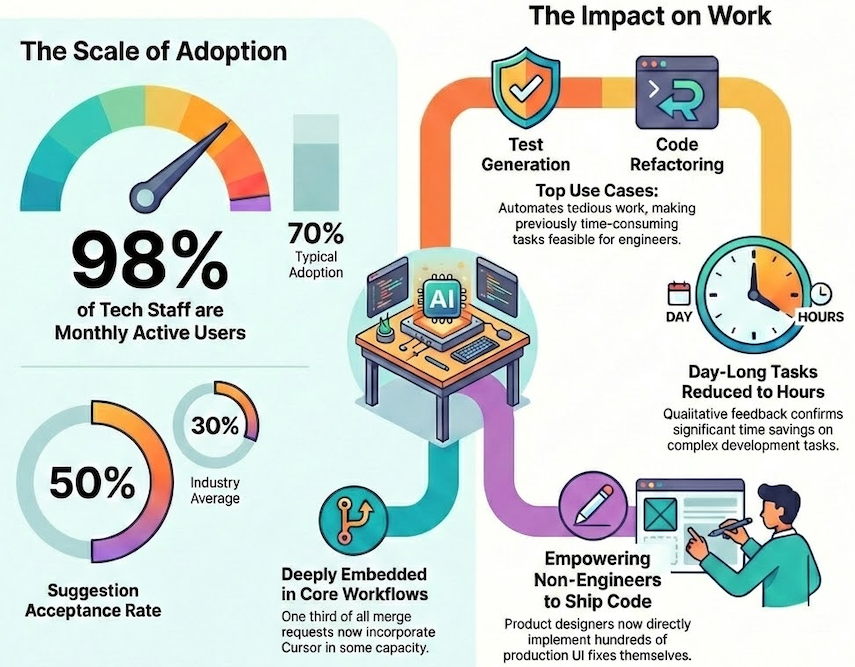
The illustration below encapsulates how Cursor is scaled across Grab, achieving rapid and widespread adoption that accelerated software development and empowered non-technical teams to build solutions.
Figure 1: Adoption overview of AI tool Cursor in Grab.
Multi-tool strategy
Grab embraces a multi-tool strategy for AI coding assistants. Rather than committing to a single solution, we experiment with multiple tools simultaneously, allowing us to compare outcomes and adopt what works. This approach keeps us flexible in a space that evolves quickly. We covered this philosophy in a previous post.
Growth
We introduced Cursor in late 2024 as one of several tools in our AI engineering toolkit. Adoption grew quickly—98% of tech Grabbers became monthly active users, and about 75% use it weekly. For comparison, Google’s 2025 State of AI-Assisted Software Development report highlights that even among high-performing teams, AI coding tool adoption seldom surpasses 70%. Notably, Cursor’s appeal extended beyond engineering, with non-technical teams incorporating it into their workflows.
A standout metric is Cursor’s suggestion acceptance rate, which is around 50%, surpassing the industry average of 30%. This indicates two key insights: first, the suggestions are sufficiently relevant for engineers to accept them half of the time; second, engineers maintain a critical review process rather than accepting suggestions indiscriminately. We attribute this relevance to continuous feedback loops and environment-specific tuning, ensuring suggestions remain aligned with Grab’s codebase and conventions.
Extent of adoption
Raw adoption figures don’t provide the complete picture. We aimed to determine whether engineers were truly incorporating Cursor into their daily workflows or merely experimenting with it sporadically.
The data indicates genuine integration. Approximately half of Cursor users engage with it 10 or more days each month, with some teams achieving full adoption. Over 98% of merge requests now incorporate Cursor in some capacity. Engineers actively share tips and workflows via a dedicated Slack channel, fostering an organic knowledge base.
Across various teams, we’ve observed significant transitions from light usage to moderate and power user levels over the past six months.
Engineer utilization patterns
The most common patterns we see are unit test generation, code refactoring, cross-repository navigation, bug fixing, and automation of routine tasks like API scaffolding or commit messages.
Test generation is particularly popular. Writing tests manually is tedious, and Cursor’s ability to generate and iteratively refine tests has become a standard part of many engineers’ workflows. Cross-repository navigation helps with onboarding and context-switching—engineers can ask Cursor questions about unfamiliar codebases rather than hunting through documentation.
Qualitative feedback confirms what the adoption numbers suggest: tasks that took a full day to complete now take hours. Engineers report tackling refactors and test additions they would have otherwise skipped due to time pressure. Cursor doesn’t just speed up existing work; it makes previously impractical work feasible.
Integration with Grab’s stack
Integrating Cursor effectively at Grab required custom tooling. We built solutions for monorepo indexing to handle Grab’s scale and to distribute preconfigured rules that align Cursor’s suggestions with Grab-specific coding conventions. This integration ensures that Cursor understands our environment rather than offering generic suggestions.
What’s next
Cursor is one tool in a broader toolkit. Our multi-tool strategy means we’re also investing in terminal-based workflows and GrabGPT for internal knowledge retrieval. Different tools suit different workflows. The aim is to empower users, not to restrict them.
Beyond engineering, we’re expanding AI-assisted development to new personas. Our AI Upskilling workshops have trained several hundred Grabbers across five countries, including executive committee members and senior leaders who have built and deployed their own apps. Non-engineers in Financial Planning and Analysis (FP&A), Operations, and regional teams are now building tools with the assitance of AI to solve their own pain points.
Our product design team has launched an initiative empowering designers to directly implement production fixes. Designers have successfully merged hundreds of merge requests, often with same-day turnaround, facilitating quicker iterations on UI fixes without the engineering queue delay. This process requires designers to be trained in Git fundamentals prior to gaining access, with initial reviews conducted by design managers.
Cursor has become part of daily work at Grab. But adoption is only half the question — the other half is impact. We’ve been running a parallel effort to measure productivity effects rigorously, using fixed-effects regression to isolate Cursor’s contribution from other factors. Early findings show a dose-response relationship: productivity gains scale with usage intensity, and the effects hold up to statistical scrutiny.
We will address the measurement methodology and present our findings in a subsequent post.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Root cause analysis during incidents is one of the most time-consuming and stressful parts of operating cloud applications. Engineers must quickly correlate telemetry data across multiple services, review deployment history, and understand complex application dependencies—all while under pressure to restore service. AWS DevOps Agent changes this paradigm by bringing autonomous investigation capabilities to your operations team, reducing mean time to resolution (MTTR) from hours to minutes.
However, the effectiveness of AWS DevOps Agent depends heavily on how you configure your Agent Spaces which control resource access boundaries. An Agent Space that’s too narrow misses critical context during investigations. One that’s too broad introduces performance overhead and complexity. This post provides best practices for setting up Agent Spaces that balance investigation capability with operational efficiency, drawing from our experience onboarding early customers and using DevOps agent across our own teams.
By the end of this post, you’ll understand how to structure Agent Spaces for optimal investigation accuracy, determine the right scope of resource access, and use Infrastructure as Code (IaC) to streamline deployment. Let’s start by understanding the foundational concept that makes all of this possible: the Agent Space itself.
What is an Agent Space and Why Does It Matter?
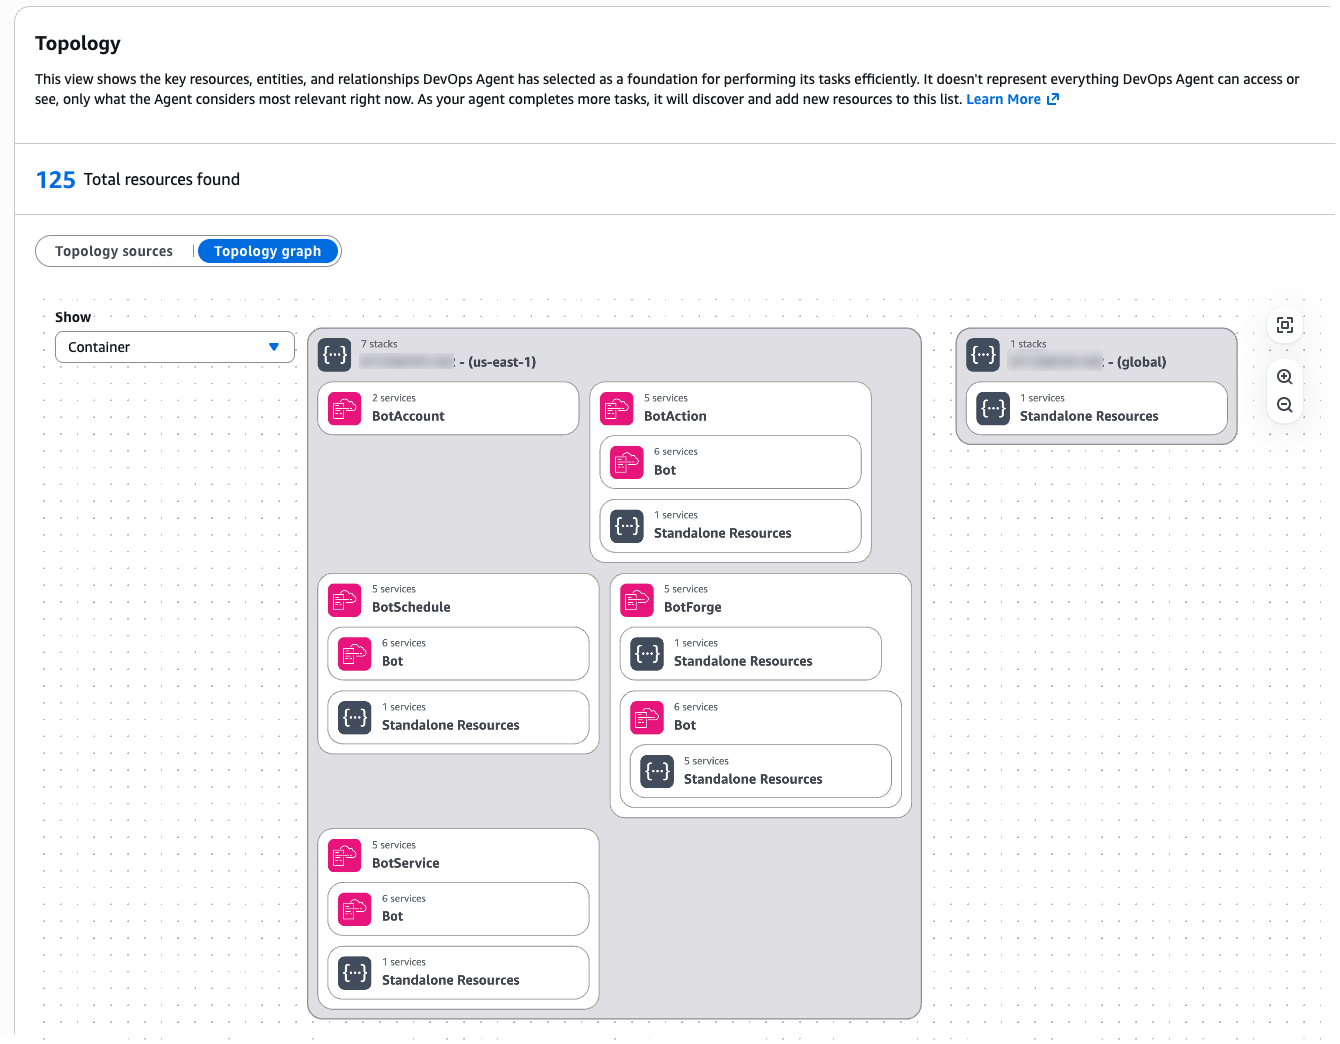
An Agent Space is a logical container that defines what AWS DevOps Agent can access and investigate. Think of it as the agent’s operational boundary—it determines which cloud accounts the agent can query, which third-party integrations are available, and who can interact with investigations.
Agent Spaces are critical because AWS DevOps Agent needs sufficient context to perform accurate root cause analysis.
When an incident occurs, the agent:
Learns your resources and their relationships across accounts
Correlates telemetry data from logs, metrics, and traces
Reviews recent changes including deployments and configuration updates
Generates and tests hypotheses by querying additional data sources
Figure 1: Agent Space Topology
If the Agent Space doesn’t include access to a critical account or integration, the agent might miss the root cause entirely. Conversely, an overly broad Agent Space introduces performance challenges as the agent considers more resource permutations during investigations.
Understanding these trade-offs between scope and performance is essential. The question becomes: how do you determine the right boundaries for your specific organization and operational model?”
Part 1: Design your Agent Space architecture
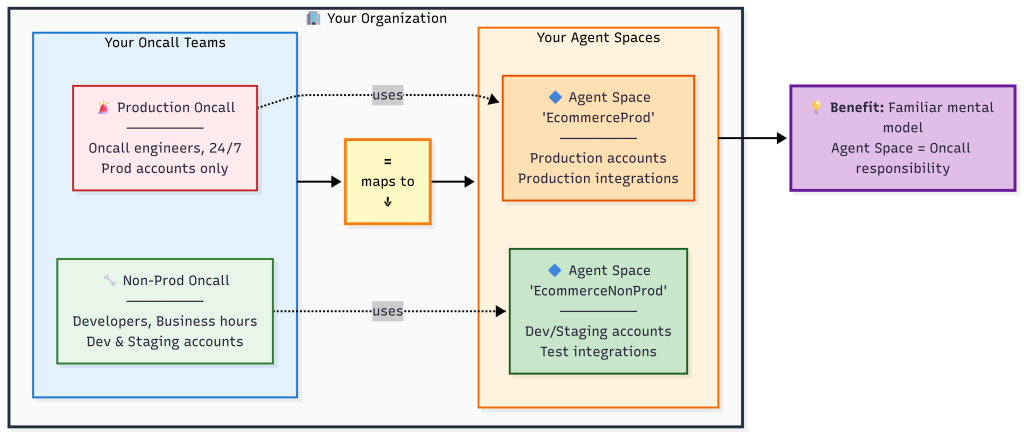
We recommend thinking about Agent Space boundaries the same way you think about on-call responsibilities: grant access to accounts relevant to the application, but separate production from non-production environments.
This approach provides several benefits:
Familiar mental model – Operations teams already understand on-call boundaries
Appropriate investigation scope – Mirrors how human engineers would investigate incidents
Two-way door decision – You can expand or narrow Agent Space scope as needs evolve
Performance balance – Provides sufficient context without overwhelming the agent
Determine Your Agent Space Boundaries
Start by mapping your application architecture to Agent Space boundaries and consider the following questions:
What defines a logical application?
Does your team own multiple independent applications? If so, create separate Agent Spaces.
Is it a monolith spanning multiple accounts? Then one Agent Space with cross-account access makes sense.
How do you organize on-call rotations?
Separate teams for production versus non-production suggests separate Agent Spaces.
One team handling all environments might work with one Agent Space per application.
What are your investigation patterns?
Do production incidents require querying dependent services in other accounts? Include those accounts.
Are environments completely isolated? Keep Agent Spaces separate.
Figure 2: Agent Space boundaries mirror on-call team responsibilities
Common Agent Space Patterns and Decision Points
Beyond the basic single-application pattern, organizations encounter more complex scenarios that require careful consideration. Here are critical patterns to address that we’ve seen customers successfully adopt:
Pattern 1: Investigations Spanning Multiple Teams. Large organizations with multiple teams (example: 3 teams managing 100+ production accounts) encounter situations where an issue originates in Team A’s infrastructure but the root cause lies in Team B’s services. The question becomes: how do you enable collaboration across Agent Spaces?
Recommended approach: Create application-specific Agent Spaces that include read-only access to shared resource accounts e.g. dependencies. Establish clear on-call escalation procedures and add them as runbooks when investigations identify cross-team root causes for efficient communication (e.g. via chat in Slack). Configure the shared service team’s resources with tags identifying which applications use them (example: app-id: ecommerce-frontend). Following a consistent tagging strategy provides investigation context for shared resources while maintaining clear resource ownership.
Pattern 2: Shared Services and Network Operations Center (NOC) Teams. Some organizations have centralized teams that provide and support shared infrastructure services (databases, networking, monitoring, security) used by multiple applications across the organization. These NOC or central operations teams need visibility into their services without requiring access to every application’s Agent Space.
Recommended approach: Create a dedicated Agent Space for the shared service team and configure an Agent Space scoped to the shared service team’s infrastructure and operational responsibilities:
Include AWS accounts containing shared databases, network infrastructure, centralized logging, and monitoring systems
Add relevant CloudFormation stacks for shared platform services
Configure IAM roles that provide read-only access to the specific resources the team supports
Include runbooks and operational procedures specific to the shared services
This follows the same principle as application-specific Agent Spaces: one Agent Space per on-call team, even when that Agent Space’s scope spans multiple applications. While shared services teams manage specific infrastructure domains, SRE teams often face an even larger challenge: operational responsibility for hundreds or thousands of applications at enterprise scale.
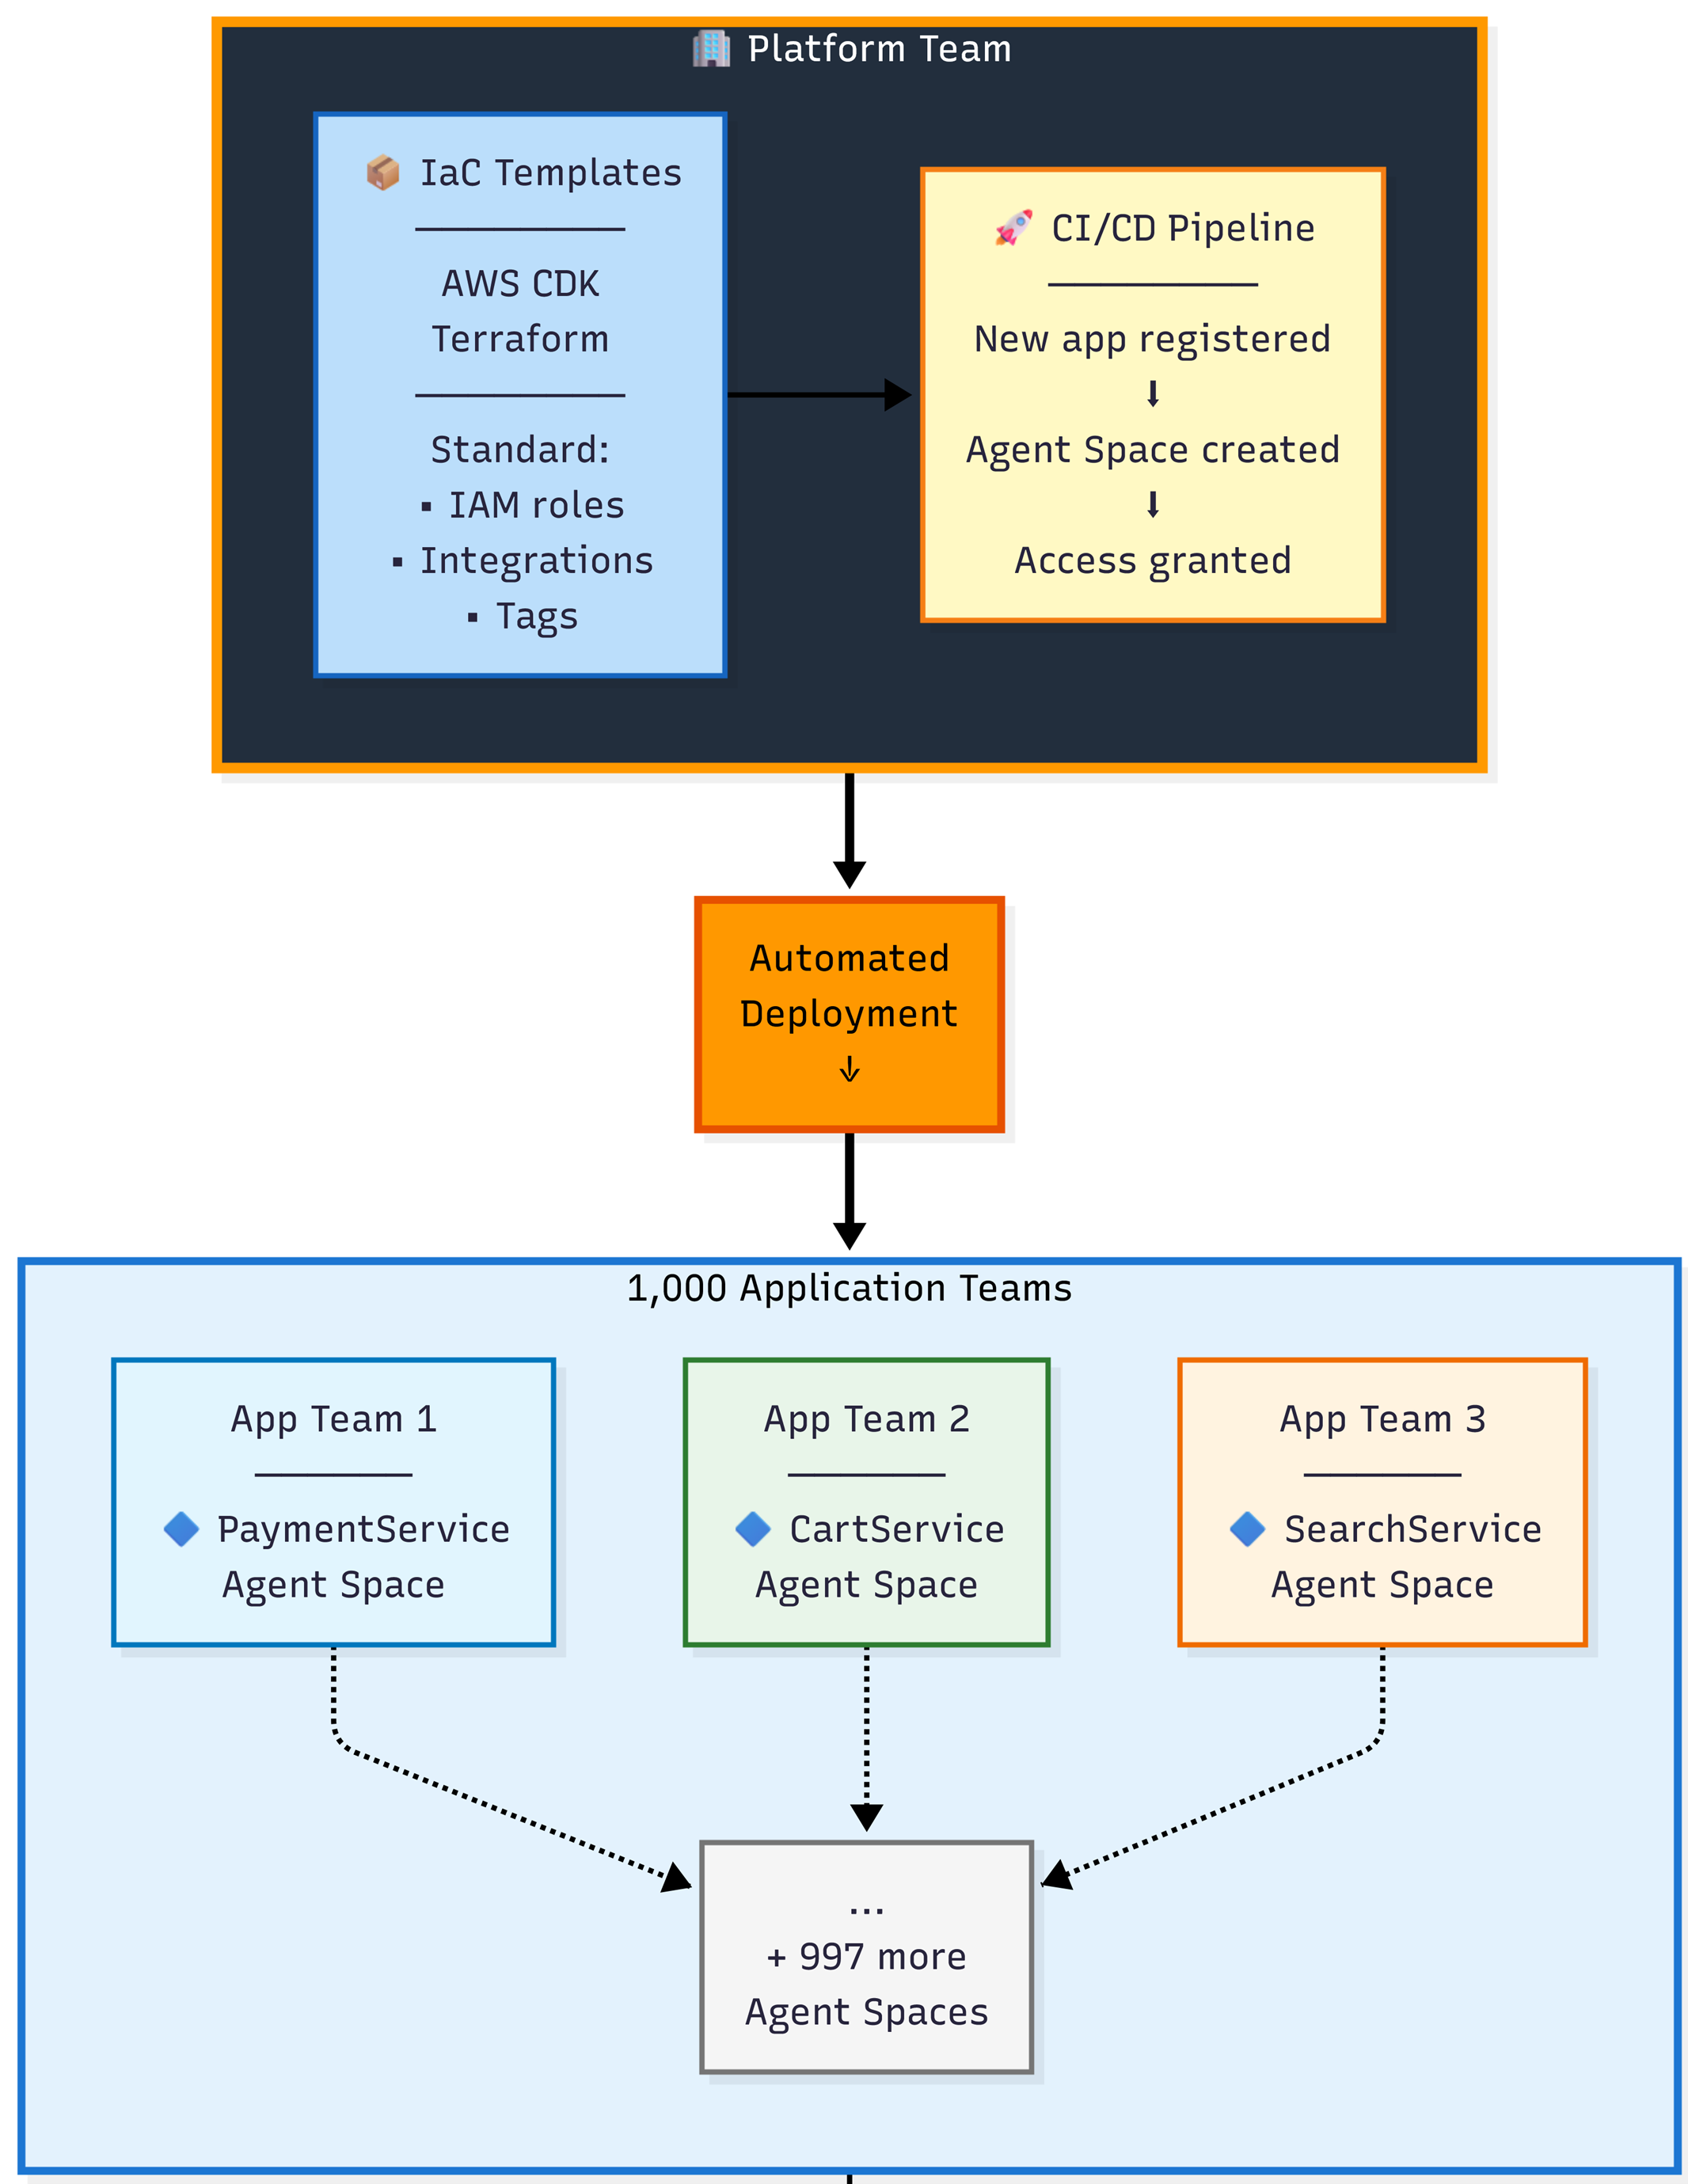
Pattern 3: Central Operations Teams Managing Many Applications. Central operations teams responsible for operational tooling across hundreds or thousands of applications can efficiently manage Agent Spaces at scale using Infrastructure as Code.
Recommended approach: Use the AWS CDK or Terraform samples available as starting points. These samples enable teams to:
Define a standardized Agent Space template with your organization’s required IAM roles, integrations, resource boundaries and governance tags
Deploy Agent Spaces programmatically as part of application onboarding workflows
Enforce compliance through AWS Config rules or service control policies
Track all Agent Spaces through consolidated billing and tagging (application-id, team, cost-center, environment)
Central operations teams manage the templates and governance policies, while application teams operate within those guardrails. This approach scales to thousands of applications with consistent configuration and automated deployment. AWS DevOps agent allows limiting agent access in an AWS account and controlling access for users to the operator console for teams to manage Agent Space access at scale.
Figure 3: Enterprise scale pattern using Infrastructure as Code
Now that you understand how to design Agent Space boundaries aligned with your team structure and scale requirements, let’s walk through the practical implementation steps to bring these architectural patterns to life.
Part 2: Implement your Agent Space architecture
This section walks you through the practical steps of creating your first Agent Space—from verifying prerequisites and configuring IAM roles across accounts to integrating observability tools, setting up access controls, and testing your configuration to ensure investigations have the context they need.
Step 1: Agent Space Prerequisites
Before setting up your first Agent Space, ensure you have:
AWS accounts – At least one AWS account where your application resources run
IAM permissions – Sufficient access to create IAM roles and policies across accounts. AWS DevOps Agent requires two distinct sets of IAM permissions:
Agent Space role permissions – The IAM role that AWS DevOps Agent assumes to query your AWS resources, access CloudWatch Logs, and discover topology. This role requires the AIOpsAssistantPolicy managed policy plus additional permissions for AWS Support and expanded capabilities. See the CLI onboarding guide for the complete role configuration.
Operator app role permissions – The IAM role that controls what human operators can do in the AWS DevOps Agent web application, such as starting investigations, viewing results, and creating AWS Support cases. This role is separate from the agent’s investigation permissions.
Service Control Policies (SCPs) – Verify that your organization’s SCPs allow AWS DevOps Agent API actions. Common issue: Teams complete Agent Space setup but investigations fail because SCPs block aidevops:* actions or bedrock:InvokeModel actions. Review your AWS Organization’s SCPs and add exceptions for DevOps Agent if needed. Note that DevOps Agent and Amazon Bedrock inference are not impacted by policies that restrict customer content to specific AWS regions—Bedrock may use US regions other than US East (N. Virginia) for stateless inference.
Observability tools – At minimum, Amazon CloudWatch (automatically available via IAM roles) and Amazon CloudTrail. For comprehensive investigations, integrate Application Performance Monitoring tools like Datadog, Dynatrace, New Relic, Grafana, or Splunk. See Connecting telemetry sources for supported integrations.
Understanding third-party integration configuration – Some third-party tools require a two-step configuration process:
Account-level registration – Tools that use OAuth (like GitHub, Dynatrace) must first be registered at the AWS account level through the DevOps Agent console. This establishes OAuth credentials that are shared across all Agent Spaces in your account.
Agent Space-level association – After registration, each Agent Space individually specifies which resources from that tool to use. For example, after registering GitHub once, Agent Space “EcommerceProd” can associate only production repositories while Agent Space “EcommerceNonProd” associates development repositories.Other tools like Datadog, New Relic, and Splunk can be directly associated with an Agent Space using API keys or tokens without separate account-level registration. CloudWatch requires no additional configuration beyond IAM roles.
Source control – GitHub or GitLab repository access for code context and deployment correlation (optional but highly recommended)
IaC tooling – AWS CDK (TypeScript/Python), Terraform, AWS CLI, or AWS Management Console for Agent Space deployment
With prerequisites verified, you’re ready to create your Agent Space and establish the IAM trust relationships that enable investigations.
Step 2: Create an Agent Space
AWS DevOps Agent requires IAM roles in each AWS account within the Agent Space boundary. The agent assumes these roles to query CloudWatch Logs, describe resources, and build application topology.
The AWS DevOps Agent is designed to retrieve operational data from multiple AWS Regions across all AWS accounts that you grant access to within the configured Agent Space, enabling comprehensive visibility into distributed infrastructure and applications regardless of their geographic deployment, while supporting multiple accounts through a configuration process that involves creating IAM roles with appropriate trust policies and permissions in secondary accounts
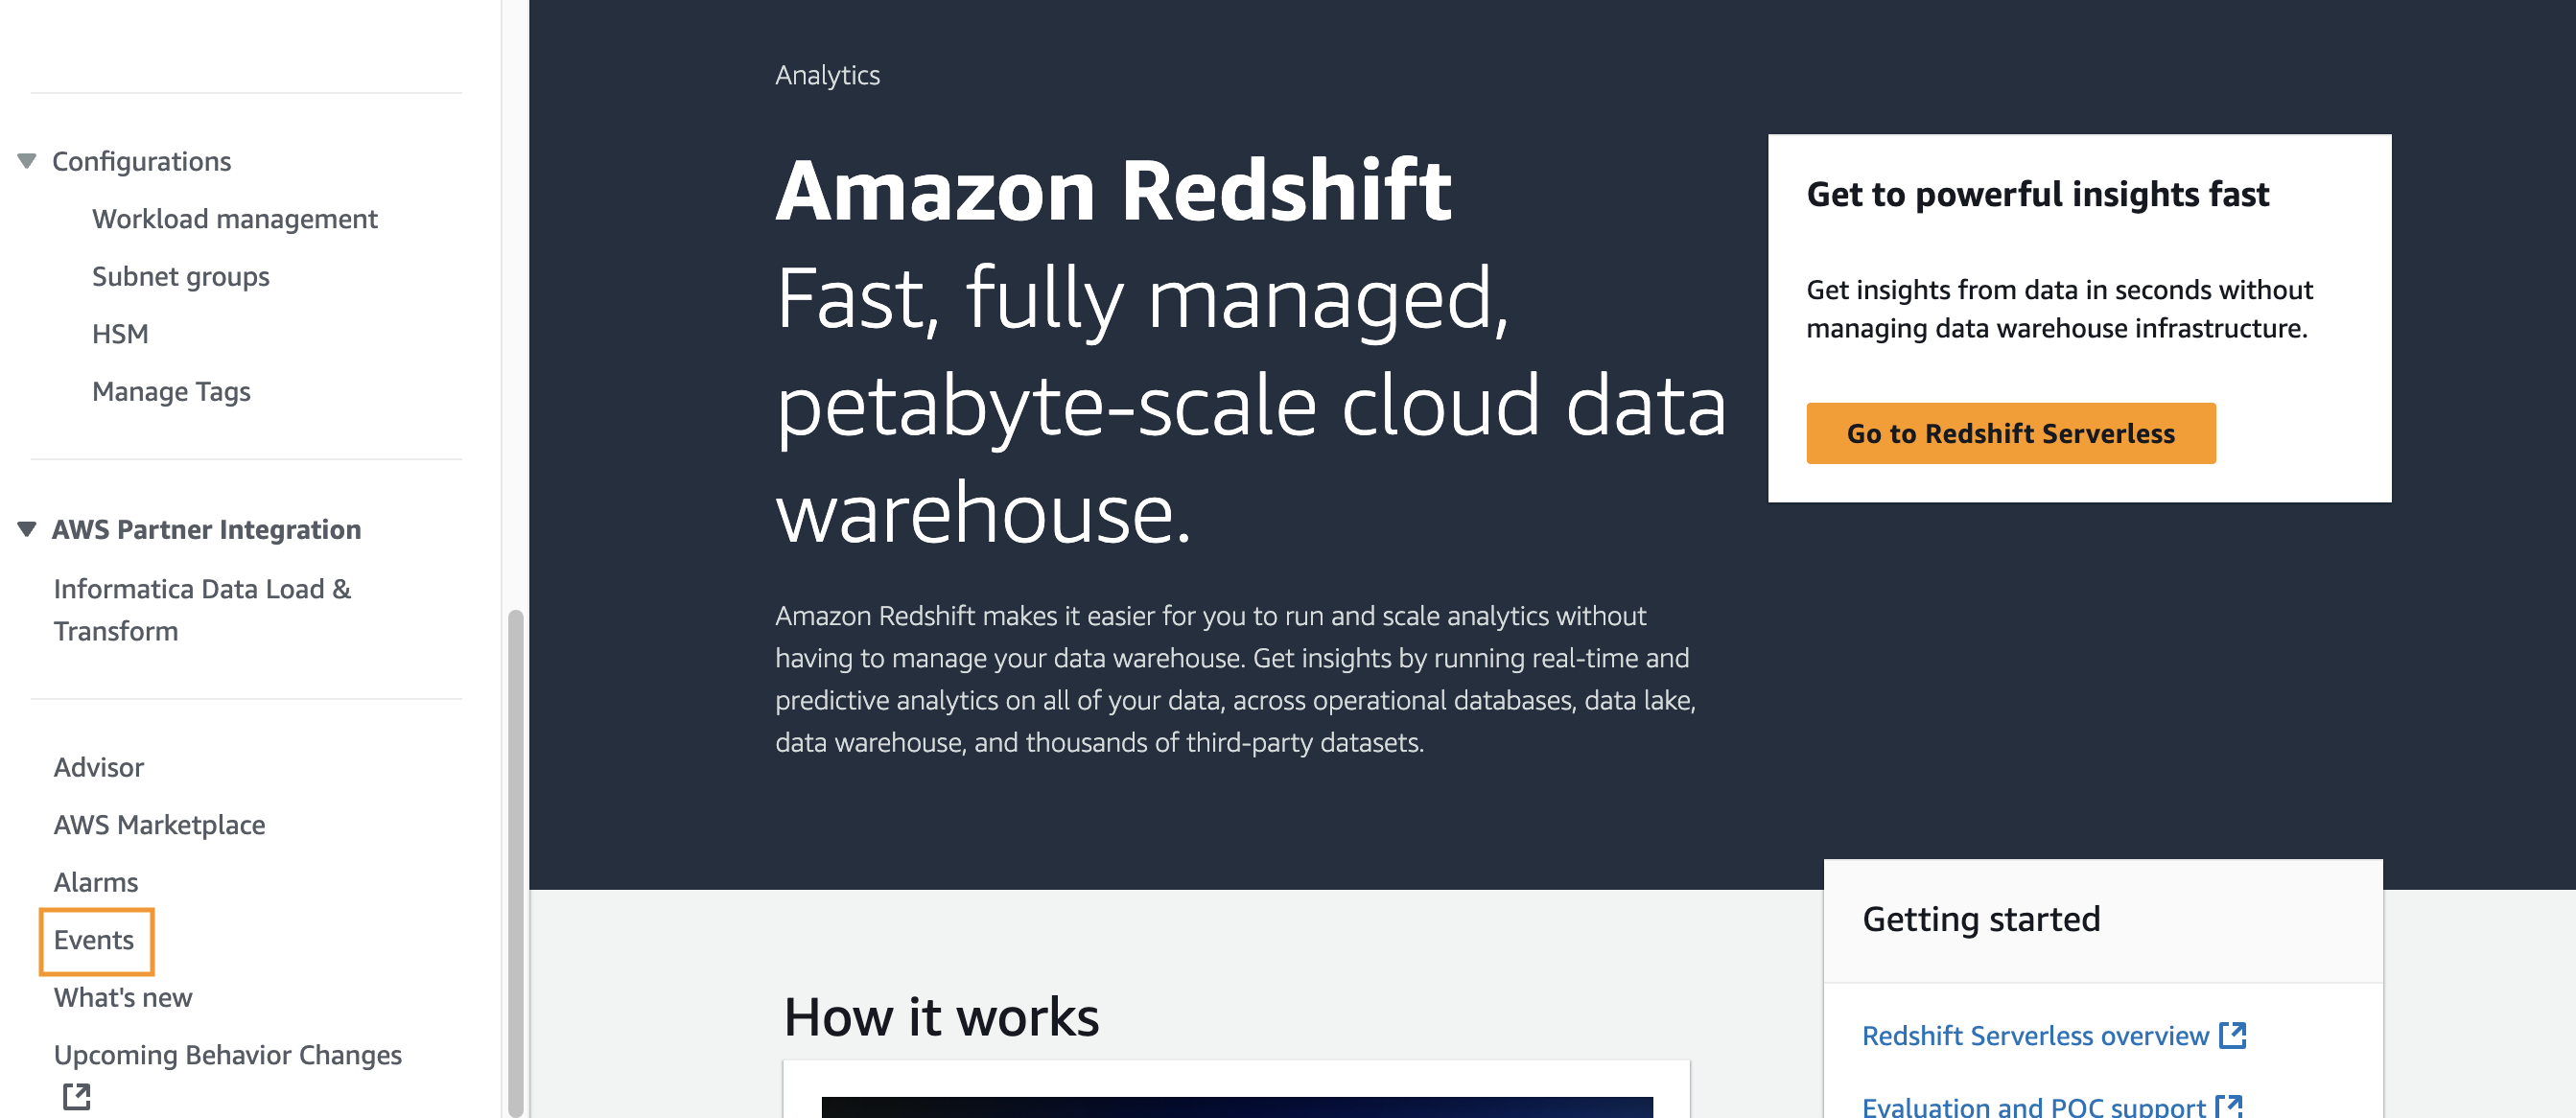
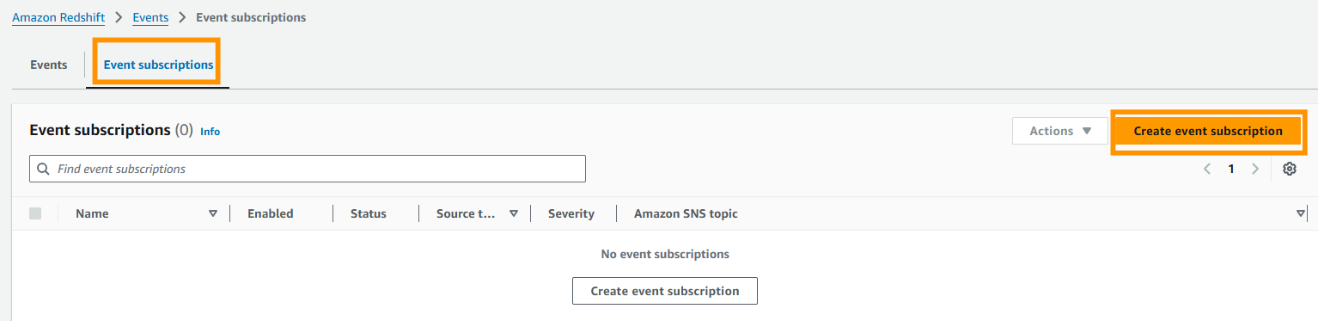
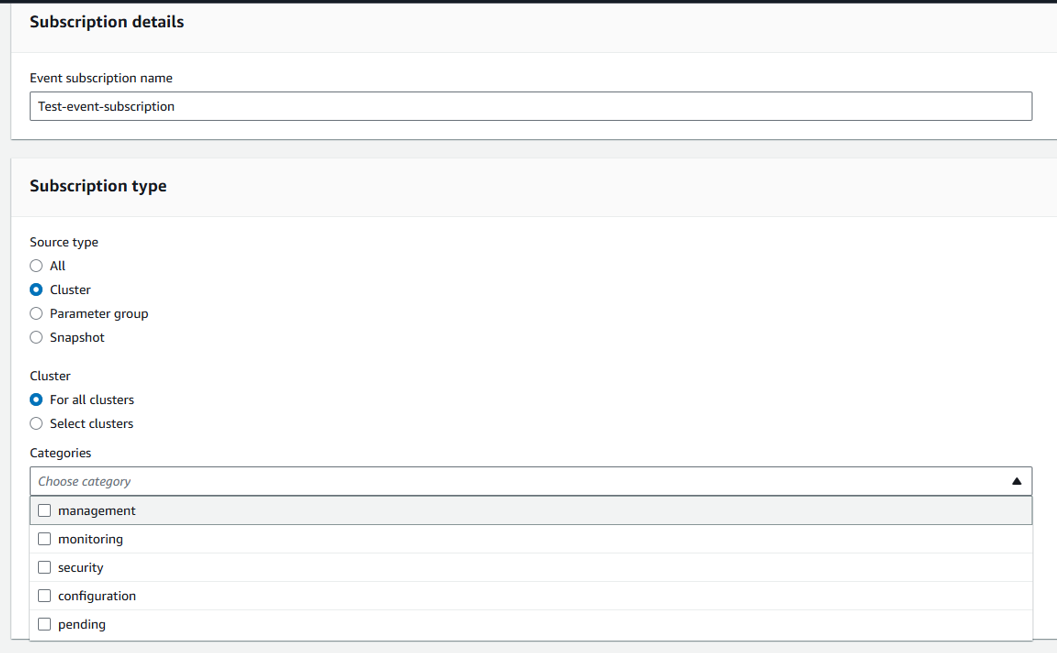
Option A: Use the AWS Console wizard Navigate to the AWS DevOps Agent console and choose Create Agent Space and follow the guided setup to create IAM roles in each target account.
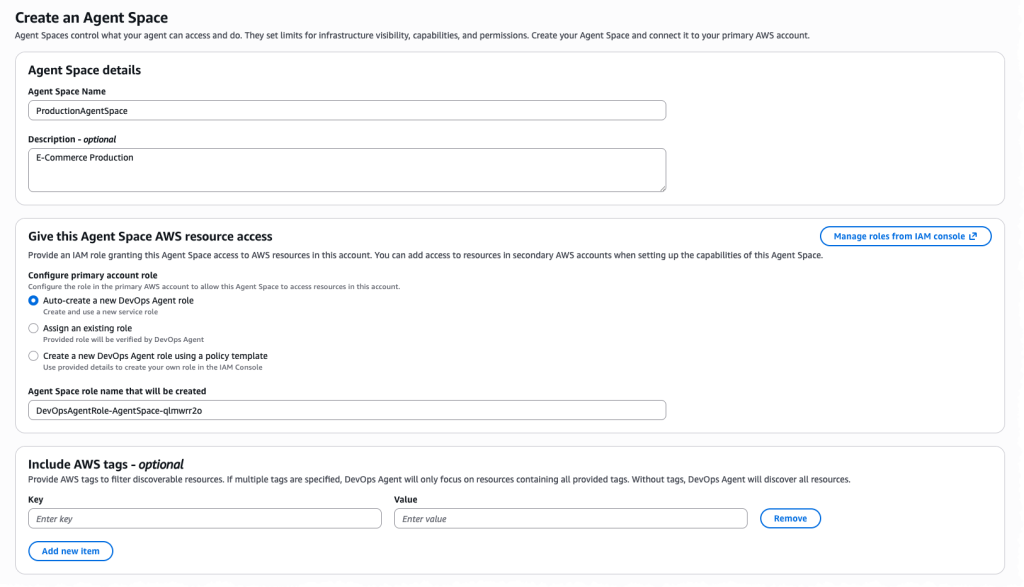
Figure 4: Creating an Agent Space in the Console
The setup wizard helps in configuring cross-account trust relationships.
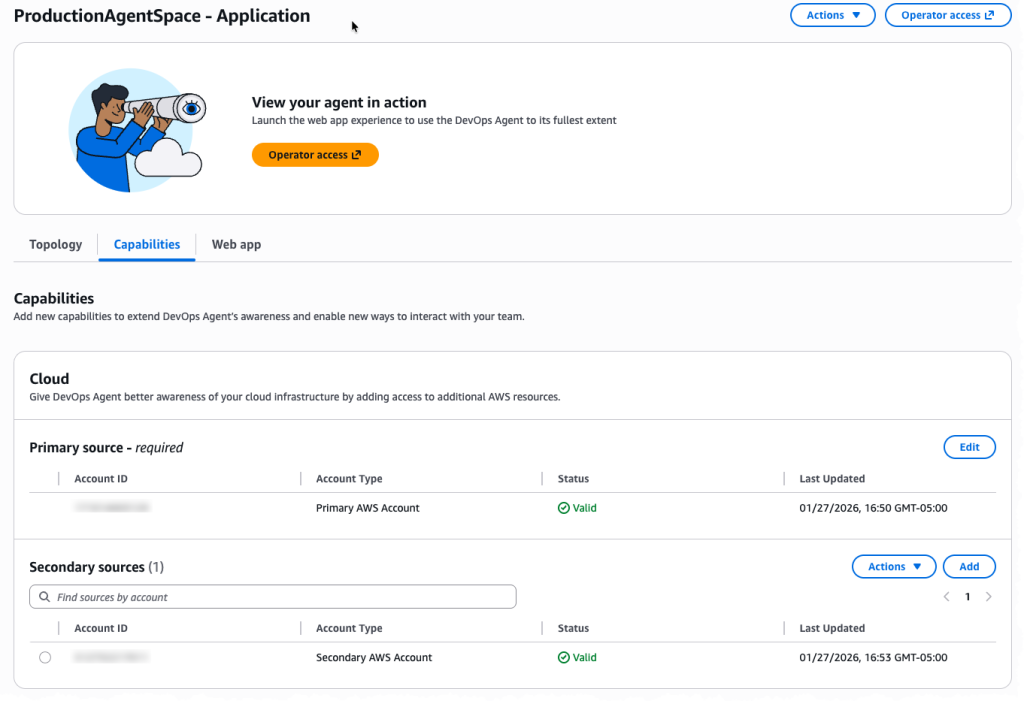
Figure 5: Multiple account configuration for your Agent Space
Option B: Use Infrastructure as Code (Recommended) We provide sample CDK and Terraform templates that automate Agent Space creation and IAM role deployment across multiple accounts.
For detailed instructions on setting up IAM roles and permissions across accounts, see the CLI Onboarding Guide.
Once your Agent Space exists and has access to AWS accounts, the next critical step is connecting the observability and development tools that provide investigation context beyond AWS native services.
Step 3: Configure Integrations
AWS DevOps Agent investigates incidents by correlating data from multiple sources. The more context available, the more accurate the root cause analysis.
Recommended integrations by priority:
Amazon CloudWatch – Provides logs, metrics, and traces from AWS services. The agent queries CloudWatch Logs Insights automatically during investigations. No additional configuration is needed if IAM roles are properly configured.
Application Performance Monitoring tools – Datadog, Dynatrace, New Relic, and Splunk provide distributed tracing, custom metrics, and application-level context. Configure via Agent Space integrations in the AWS Console.
Code repositories – GitHub or GitLab integration enables the agent to review recent deployments and code changes. Requires OAuth or personal access token.
CI/CD pipelines – GitHub Actions or GitLab workflows help the agent correlate incidents with deployment timing. Configured alongside code repository integration.
Communication Channels – Slack and ServiceNow integration enables DevOps Agent to post real-time investigation updates to team channels and automatically update incident tickets with findings, root cause analysis, and recommended mitigation steps throughout the investigation lifecycle.
Advanced Integrations
Beyond built-in integrations, AWS DevOps Agent supports webhook triggered investigations and custom MCP (Model Context Protocol) servers so you can bring-your-own observability tools.
Webhook configuration for investigation triggers Webhooks allow external systems (Grafana, Prometheus, PagerDuty, custom monitoring tools) to automatically trigger DevOps Agent investigations when incidents occur. Each Agent Space receives a unique webhook URL that accepts JSON payloads describing the incident.
Common configuration pitfalls:
Webhook authentication: Webhooks use HMAC signatures for security. Store the webhook secret in AWS Secrets Manager and rotate it according to your security policies.
Payload format: Ensure your monitoring tool sends incident context including timestamps, affected resources, and symptom descriptions. Richer context enables more accurate investigations.
Bring-your-own MCP servers If you use observability tools beyond the built-in integrations (Grafana, Prometheus, custom telemetry systems), you can connect them via MCP servers. MCP servers expose your tool’s data through a standardized protocol that DevOps Agent queries during investigations.
Key requirements for MCP servers:
Publicly accessible HTTPS endpoint: MCP servers must be reachable from the public internet. VPC-hosted servers are not currently supported.
Read-only tools only: For security, only expose MCP tools that perform read operations. Write operations introduce prompt injection risks.
Tool allowlisting: Register MCP servers at the account level, then selectively enable specific tools per Agent Space. Don’t grant access to all tools—choose only those relevant to investigations.
Common MCP setup errors:
Authentication misconfiguration: MCP servers support OAuth 2.0 or API key authentication. Verify your OAuth client credentials are correct and that token exchange URLs are accessible from AWS infrastructure.
Tool name length: MCP tool names have a maximum length of 64 characters. Longer names will fail registration.
Endpoint URL format: Use the full HTTPS URL including path. Example: https://mcp.example.com/v1/mcp not just mcp.example.com.
For comprehensive MCP server setup including authentication configuration, see Connecting MCP Servers.
Testing your integrations After configuring webhooks or MCP servers, trigger a test investigation to verify connectivity:
For webhooks: Send a test payload from your monitoring tool and verify the investigation starts in the DevOps Agent web app
For MCP servers: Start an investigation manually and check the agent journal to confirm it successfully called your MCP tools
Review any errors in AWS CloudTrail logs which capture all DevOps Agent API calls including integration attempts
With your data sources connected, you now need to ensure the right people have appropriate access to investigations while maintaining security boundaries.
Step 4: Configure Access Controls
Agent Spaces support fine-grained access controls to ensure only authorized team members can interact with investigations.
Access control considerations:
Who should view investigations? Typically on-call engineers, SREs, and DevOps engineers. Consider including security teams for security-related incidents.
Who should create AWS Support cases? Typically on-call leads and senior engineers. Restrict this permission to prevent excessive case creation.
Who should modify Agent Space configuration? Typically central operations or infrastructure teams. Separate this from day-to-day investigation access.
IAM-based access control:
AWS DevOps Agent uses IAM policies to control access to Agent Spaces. Attach policies to IAM users, groups, or roles:
AWS DevOps Agent operates within your AWS environment with privileged access to operational data across multiple accounts. While general security foundations apply, Agent Space configuration introduces specific considerations. For comprehensive security guidance, see the AWS DevOps Agent Security documentation.
Access controls are in place—now it’s time to validate that your Agent Space configuration provides the investigation coverage you need.
Step 5: Test and Iterate
Agent Space configuration is a two-way door decision. Start with a focused scope and expand based on investigation results.
Testing your Agent Space:
Trigger a test investigation using the AWS DevOps Agent web app.
Start an investigation and provide symptoms such as “High latency on /api/checkout endpoint”.
Observe which resources the agent queries.
Review investigation completeness. Did the agent identify the root cause?
Were any accounts or services missing from the investigation?
Did the agent have sufficient telemetry data?
Adjust Agent Space boundaries based on results.
Add accounts if investigations lack context.
Add integrations if telemetry gaps exist.
Narrow scope if performance degrades.
Conclusion
AWS DevOps Agent transforms incident response from a manual, time-consuming process into an autonomous, data-driven investigation. However, the agent’s effectiveness depends on proper Agent Space configuration. By following the on-call based approach—granting access to accounts relevant to your application while separating production from non-production environments—you provide sufficient context for accurate root cause analysis without introducing unnecessary complexity.
Key takeaways:
Think on-call boundaries – Agent Space scope should mirror how your team investigates incidents
Use Infrastructure as Code – CDK and Terraform templates ensure consistent, repeatable deployments
Integrate observability tools – More data sources equals more accurate investigations
Iterate based on results – Expand or narrow Agent Space scope as investigation patterns emerge
We’re committed to making AWS DevOps Agent easier to adopt and more accurate in solving customer problems. Your Agent Space setup is the foundation for achieving fast, reliable incident resolution. Have questions or feedback? Leave a comment below.
We have received the sad news that Didier Spaier, maintainer of the
blind-friendly Slackware-based Slint distribution, has recently passed
away. Philippe Delavalade, who posted the announcement to the
Slint mailing list, said:
Early 2015, I asked on the slackware list if brltty could be added
in the installer; Didier answered promptly that he could do it on
slint. Afterwards, he worked hard so that slint became as accessible
as possible for visually impaired people.
You all know that all these years, he tried and succeeded to answer
as quickly as possible to our issues and questions.
The Open Source Initiative (OSI) has announced
that it will not be holding the 2026 spring board election. Instead,
it will be creating a working group to “review and improve OSI’s
board member selection process” and provide recommendations by
September 2026:
The public election process was designed to gather community
priorities and improve board member selection, while final
appointments remained with the board.
Over time, that nuance has become a source of understandable
confusion for community members. Many reasonably expected elections to
function as elections normally do, and in fact, the board has
generally adopted the electorate’s recommendations. When a process
feels unclear, trust suffers. When trust suffers, engagement becomes
harder. This is especially problematic for an organization whose
mission depends on legitimacy and credibility. […]
OSI tried its experiment for the right reasons, but a variety of
factors resulted in “elections” that are performatively democratic
while being gameable and representative of only a small group, and
we’ve learned from the results. Now we are making space to align our
director selection process with our bylaws, to rebuild trust, and to
develop better, more durable and truly representative participation in
which the global stakeholder community can be heard.
This is a guest post by Jake J. Dalli, Data Platform Team Lead at Tipico, in partnership with AWS.
Tipico is the number one name in sports betting in Germany. Every day, we connect millions of fans to the thrill of sport, combining technology, passion, and trust to deliver fast, secure, and exciting betting, both online and in more than a thousand retail shops across Germany. We also bring this experience to Austria, where we proudly operate a strong sports betting business.
To support critical needs such as product monitoring, customer insights, and revenue assurance, our central data function needed to provide the tools for several cross-functional analytics and data science teams to run scalable batch workloads on the existing data warehouse, powered by Amazon Redshift. The workloads of Tipico’s data community included extract, transform, and load (ELT), statistical modeling, machine learning (ML) training, and reporting across diverse frameworks and languages.
In the past, analytics teams operated in isolation, distinct from each other and the central data function. Different teams maintained their own set of tools, often performing the same function and creating data silos. Lack of visibility meant a lack of standardization. This siloed approach slowed down the delivery of insights and prevented the company from achieving a unified data strategy that ensured availability and scalability.
The need to introduce a single, unified platform that promoted visibility and collaboration became clear. However, the diversity of workloads brought another layer of complexity. Teams needed to tackle different types of problems and brought distinct skillsets and preferences in tooling. Analysts might rely heavily on SQL and business intelligence (BI) platforms, whereas data scientists preferred Python or R, and engineers leaned on containerized workflows or orchestration frameworks.
Our goal was to architect a new system that supports diversity while maintaining operational control, delivering an open orchestration platform with built-in security isolation, scheduling, retry mechanisms, fine-grained role-based access control (RBAC), and governance features such as two-person approval for production workflows. We achieved this by designing a system with the following principles:
Bring Your Own Container (BYOC) – Teams are given the flexibility to package their workloads as containers and are free to choose dependencies, libraries, or runtime environments. For teams with highly specialized workloads, this meant that they could work in a setup tailored to their needs while also operating within a harmonized platform. On the other hand, teams that didn’t require fully customized environments could redesign their workloads to align with existing workloads.
Centralized orchestration for full transparency – All teams can see all workflows and build interdependencies between them
Shared orchestration, isolated compute – Workloads run in team-specific Docker containers within a unified compute environment, providing scalability while keeping execution traceable to each team.
Standardized interfaces, flexible execution – Common patterns (operators, hooks, logging, or monitoring) reduce complexity, and teams retain freedom to innovate within their containers.
Cross-team approvals for critical workflows stored inside version control – Changes follow a four-eye principle, requiring review and approval from another team before execution, providing accountability and reducing risk. This allowed our core data function to monitor and contribute suggestions to work across different analytics teams.
We devised a system wherein orchestration and execution of tasks operate on shared infrastructure, which teams interact with through domain-specific infrastructure. In Tipico’s case, each team pushes images to team-owned container instances. Such containers provide code for workflows, including execution of ELT pipelines or transformations on top of domain-specific data lakes.
The following diagram shows the solution architecture.
The technical challenge was to architect a flexible and high-performance orchestration layer that could scale reliably while also remaining framework-agnostic, integrating seamlessly with existing infrastructure.
When designing our system, we were aware of the several container orchestration solutions offered by Amazon Web Services (AWS), including Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), and AWS Batch, among others. In the end, the team selected AWS Batch because it abstracts away cluster management, provides elastic scaling, and inherently supports batch workloads as a design feature.
Solution details
Before adopting the current solution, Tipico experimented with operating a self-managed Apache Airflow setup. Although it was functional, it became increasingly burdensome to maintain. The shift toward a managed and scalable solution was driven by the need to focus more on empowering teams to deliver rather than maintaining the infrastructure. Tipico replatformed the central orchestration solution using Amazon MWAA and AWS Batch.
Amazon MWAA is a fully managed service that simplifies running open source Apache Airflow on AWS. Users can build and execute data processing workflows while integrating seamlessly with various AWS services, which means developers and data engineers can concentrate on building workflows rather than managing infrastructure.
AWS Batch is a fully managed service that simplifies batch computing in the cloud so users can run batch jobs without needing to provision, manage, or maintain clusters. It automates resource provisioning and workload distribution, with users only paying for the underlying AWS resources consumed.
The new design provides a unified framework where analytics workloads are containerized, orchestrated, and executed on scalable compute and integrated with persistent storage:
Containerization – Analytics workloads are packaged into Docker containers, with dependencies bundled to provide reproducibility. These images are versioned and stored in Amazon Elastic Container Registry (Amazon ECR). This approach decouples execution from infrastructure and enables consistent behavior across environments.
Workflow orchestration – Airflow Directed Acyclic Graphs (DAGs) are version-controlled in Git and deployed to Amazon MWAA using a continuous integration and continuous delivery (CI/CD) pipeline. Amazon MWAA schedules and orchestrates tasks, triggering AWS Batch jobs using custom operators. Logs and metrics are streamed to Amazon CloudWatch, enabling real-time observability and alerting.
Data persistence – Workflows interact with Amazon Simple Storage Service (Amazon S3) for durable storage of inputs, outputs, and intermediate artifacts. Amazon Elastic File System (Amazon EFS) is mounted to Amazon MWAA for fast access to shared code and configuration files, synchronized continuously from the Git repository.
Scalable compute – Amazon MWAA triggers AWS Batch jobs using standardized job definitions. These jobs run in elastic compute environments such as Amazon Elastic Compute Cloud (Amazon EC2) or AWS Fargate, with secrets securely injected using AWS Secrets Manager. AWS Batch environments auto scale based on workload demand, optimizing cost and performance.
Security and governance – AWS Identity and Access Management (IAM) roles are scoped per team and workload, providing least-privilege access. Job executions are logged and auditable, with fine-grained access control enforced across Amazon S3, Amazon ECR, and AWS Batch.
Common operators
To streamline the execution of batch jobs across teams, we developed a shared operator that wraps the built-in Airflow AWS Batch operator. This abstraction simplifies the execution of containerized workloads by encapsulating common logic such as:
Job definition selection
Job queue targeting
Environment variable injection
Secrets resolution
Retry policies and logging configuration
Parameterization is handled using Airflow Variables and XComs, enabling dynamic behavior across DAG runs. The operator is maintained in a shared Git repository, versioned and centrally governed, but accessible to all teams.
To further accelerate development, some teams use a DAG Factory pattern, which programmatically generates DAGs from configuration files. This reduces boilerplate and enforces consistency so teams can define new workflows declaratively.
By standardizing this operator and supporting patterns, Tipico reduces onboarding friction, promotes reuse, and provides consistent observability and error handling across the analytics ecosystem.
Governance
Governance is enforced through a combination of fine-grained IAM roles, AWS IAM Identity Center and automated role mapping. Each team is assigned a dedicated IAM role, which governs access to AWS services such as Amazon S3, Amazon ECR, AWS Batch and Secrets Manager. These roles are tightly scoped to minimize the extent of damage and provide traceability.
Given that the airflow environment runs version 2.9.2, which doesn’t support multi-tenant access, Tipico developed a custom component that dynamically maps AWS IAM roles to Airflow roles. The component, which executes periodically using Airflow itself, dynamically syncs IAM role assignments with Airflow’s internal RBAC model. Airflow tags are used to govern access to different DAGs, governing which teams have access to execute or modify the settings on the DAG. This aligns access permissions remain with organizational structure and team responsibilities.
Adoption
The shift toward a managed, scalable solution was driven by the need for greater team autonomy, standardization, and scalability. The journey began with a single analytics team validating the new approach. When it was successful, the platform team generalized the solution and rolled it out incrementally to other teams, refining it with each iteration.One of the biggest challenges was migrating legacy code, which often included outdated logic and undocumented dependencies. To support adoption, Tipico introduced a structured onboarding process with hands-on training, real use cases, and internal champions. In some cases, teams also had to adopt Git for the first time—marking a broader shift toward modern engineering practices within the analytics organization.
Key benefits
One of the most valuable outcomes of our new architecture that is primarily built around Amazon MWAA and AWS Batch is to accelerate analytics teams’ time to value. Analysts can now focus on building transformation logic and workloads without worrying about the underlying infrastructure. With this system, analysts can rely on preprepared integrations and analytics patterns used across different teams, supported by standard interfaces developed by the core data team.
Aside from building analytics on Amazon Redshift, the orchestration solution also interfaces with several other analytics services such as Amazon Athena and AWS Glue ETL, providing maximum flexibility on the type of workloads being delivered. Teams within the organization have also shared practices in using different frameworks, such as dbt Labs, to reuse custom developments to carry out standard processes.
Another valuable outcome is the ability to clearly segregate costs across teams. Within the architecture, Airflow delegates heavy lifting to AWS Batch, providing task isolation that spans beyond Airflow’s built-in workers. Through this, we gain granular visibility into resource usage and accurate cost attribution, promoting financial accountability across the organization.
Finally, the platform also provides embedded governance and security, with RBAC and standardized secrets management providing an operationalized model for securing and governing working flows across different teams.
Teams can now focus on building and iterating quickly, knowing that the surrounding structures provide full transparency and are coherent with the organization’s governance, architecture, and FinOps goals. At the same time, centralized orchestration fosters a collaborative environment where teams can discover, reuse, and build upon each other’s workflows, driving innovation and reducing duplication across the data landscape.
Conclusion
By reimagining our orchestration layer with Amazon MWAA and AWS Batch, Tipico has unlocked a new level of agility and transparency across its data workflows.
Previously, analytics teams faced long lead times, often stretching into weeks, to implement new reporting use cases. Much of this time was spent identifying datasets, aligning transformation logic, discovering integration options, and navigating inconsistent quality assurance processes. Today, that has changed. Analysts can now develop and deploy a use case within a single business day, shifting their focus from groundwork to action.
The modern architecture empowers teams to move faster and more independently within a secure, governed, and scalable framework. The result is a collaborative data ecosystem where experimentation is encouraged, operational overhead is reduced, and insights are delivered at speed.
Game studios generate massive amounts of player and gameplay telemetry, but transforming that data into meaningful insights is often slow, technical, and dependent on SQL expertise. With the new Amazon Redshift integration for Amazon Bedrock Knowledge Bases, teams can unlock instant, AI-powered analytics by asking questions in natural language. Analysts, product managers, and designers can now explore Amazon Redshift data conversationally—no query writing required—and Amazon Bedrock automatically generates optimized SQL, executes it on Amazon Redshift, and returns clear, actionable answers. This brings together the scale and performance of Amazon Redshift with the intelligence of Amazon Bedrock, enabling faster decisions, deeper player understanding, and more engaging game experiences.
Amazon Redshift can be used as a structured data source for Amazon Bedrock Knowledge Bases, allowing for natural language querying and retrieval of information from Amazon Redshift. Amazon Bedrock Knowledge Bases can transform natural language queries into SQL queries, so users can retrieve data directly from the source without needing to move or preprocess the data. A game analyst can now ask, “How many players completed all the levels in a game?” or “List the top 5 players by the number of times the game was played,” and Amazon Bedrock Knowledge Bases automatically translates that query into SQL, runs the query against Amazon Redshift, and returns the results—or even provides a summarized narrative response.
To generate accurate SQL queries, Amazon Bedrock Knowledge Bases uses database schema, previous query history, and other domain or business knowledge such as table and column annotations that are provided about the data sources. In this post, we discuss some of the best practices to improve accuracy while interacting with Amazon Bedrock using Amazon Redshift as the knowledge base.
Solution overview
In this post, we illustrate the best practices using gaming industry use cases. You will converse with players and their game attempts data in natural language and get the response back in natural language. In the process, you will learn the best practices. To follow along with the use case, follow these high-level steps:
Load game attempts data into the Redshift cluster.
Create a knowledge base in Amazon Bedrock and sync it with the Amazon Redshift data store.
Review the approaches and best practices to improve the accuracy of response from the knowledge base.
Complete the detailed walkthrough for defining and using curated queries to improve the accuracy of responses from the knowledge base.
Prerequisites
To implement the solution, you need to complete the following prerequisites:
Run the following SQL to create the data tables to store games attempts and player details:
CREATE TABLE game_attempts (
    player_id numeric(10, 0), -- Player ID.
    level_id numeric(5, 0), -- Game level ID
    f_success integer, -- Indicates whether user completed the level (1: completed, 0: fails).
    f_duration real, -- duration of the attempt.  Units in seconds
    f_reststep real, -- The ratio of the remaining steps to the limited steps.  Failure is 0.
    f_help integer, -- Whether extra help, such as props and hints, was used.  1- used, 0- not used
    game_time timestamp, -- Attempt timestamp
    bp_used boolean -- Whether bonus packages used or not.  true: used, false: not used.
);
CREATE TABLE players (
	player_id numeric(10, 0), -- Player ID
	lost_label boolean, -- Indicated if user retained or lost.  true: lost ,  false: retained
	bp_category integer -- bonus package category codes
);
Upload the downloaded files into your newly created S3 bucket.
Using the following COPY command statements, load the datasets from Amazon S3 into the new tables you created in Amazon Redshift. Replace <<your_s3_bucket>> with the name of your S3 bucket and <<your_region>> with your AWS Region:
COPY game_attempts
FROM 's3://<<your_s3_bucket>>/game_attempts.csv'
IAM_ROLE DEFAULT
FORMAT AS CSV
IGNOREHEADER 1;
COPY players
FROM 's3://<<your_s3_bucket>>/players.csv'
IAM_ROLE DEFAULT
FORMAT AS CSV
IGNOREHEADER 1;
Create knowledge base and sync
To create a knowledge base and sync your data store with your knowledge base, complete these steps:
If you’re not getting the expected response from the knowledge base, you can consider these key strategies:
Provide additional information in the Query Generation Configuration. The knowledge base’s response accuracy can be improved by providing supplementary information and context to help it better understand your specific use case.
Use representative sample queries. Running example queries that reflect common use cases helps train the knowledge base on your database’s specific patterns and conventions.
Consider a database that stores player information using country codes rather than full country names. By running sample queries that demonstrate the relationship between country names and their corresponding codes (for example, “USA” for “United States”), you help the knowledge base understand how to properly translate user requests that reference full country names into queries using the correct country codes. This approach helps connect natural language requests and your database’s specific implementation details, resulting in more accurate query generation.
Before we dive into more optimizations options, let’s explore how you can personalize the query engine to generate queries for a specific query engine. In this walkthrough, we use Amazon Redshift. Amazon Bedrock Knowledge Bases analyzes three key components to generate accurate SQL queries:
Database metadata
Query configurations
Historical query and conversation data
The following graphic illustrates this flow.
You can configure these settings to enhance query accuracy in two ways:
When creating a new Amazon Redshift knowledge base
By editing the query engine settings of an existing knowledge base
To configure setting when editing the query engine of an existing knowledge base, follow these steps:
On the Amazon Bedrock console in the left navigation pane, choose Knowledge Bases and select your Redshift Knowledge Base.
Choose your query engine and choose Edit,
Configure below parameters in (Optional) Query configurations section as shown in following screenshot:
Table and column descriptions
Table and column inclusions/exclusions
Curated queries
Let’s explore the available query configuration options in more detail to understand how these help the knowledge base generate a more accurate response.
Table and column descriptions provide essential metadata that helps Amazon Bedrock Knowledge Bases understand your data structure and generate more accurate SQL queries. These descriptions can include table and column purposes, usage guidelines, business context, and data relationships.
Follow these best practices for descriptions:
Use clear, specific names instead of abstract identifiers
Include business context for technical fields
Define relationships between related columns
For example, consider a gaming table with timestamp columns named t1, t2, and t3. Adding these descriptions helps the knowledge base generate appropriate queries. For example, if t1 is play start time, t2 is play end time, and t3 is record creation time, adding these descriptions will indicate to the knowledge base to use t2–t1 for finding the game duration.
Curated queries are a set of predefined question and answer examples. Questions are written as natural language queries (NLQs) and answers are the corresponding SQL query. These examples help the SQL generation process by providing examples of the kinds of queries that should be generated. They serve as reference points to improve the accuracy and relevance of generative SQL outputs. Using this option, you can provide some example queries to the knowledge base for it understand custom vocabulary also. For example, if the country field in the table is populated with a country code, adding an example query will help the knowledge base to convert the country name to a country code before running the query to answer questions on the data of players in a specific country. You can also provide some example complex queries to help the knowledge base to respond to more complex questions. The following is an example query that can be added to the knowledge base:
Select count(*) from players_address where country = ‘USA’;
With table and column inclusion and exclusion, you can specify a set of tables or columns to be included or excluded for SQL generation. This field is crucial if you want to limit the scope of SQL queries to a defined subset of available tables or columns. This option can help optimize the generation process by reducing unnecessary table or column references. You can also use this option to:
Exclude redundant tables, for example, those generated by copying the original table to run a complex analysis
Exclude tables and columns containing sensitive data
If you specify inclusions, all other tables and columns are ignored. If you specify exclusions, the tables and columns you specify are ignored.
Walkthrough for defining and using curated queries to improve accuracy
To define and use curated queries to improve accuracy, complete the following steps.
On the AWS Management Console, navigate to Amazon Bedrock and in the left navigation pane, choose Knowledge Bases. Select the knowledge base you created with Amazon Redshift.
Choose Test Knowledge Base, as shown in the following screenshot, to validate the accuracy of the knowledge base response.
On the Test Knowledge Base screen under Retrieval and response generation, choose Retrieval and response generation: data sources and model.
Choose Select model to pick a large language model (LLM) to convert the SQL query response from the knowledge base to a natural language response.
Choose Nova Pro in the popup and choose Apply, as shown in the following screenshot.
Now you have Amazon Nova Pro connected to your knowledge base to respond to your queries based on the data available in Amazon Redshift. You can ask some questions and verify them with actual data in Amazon Redshift. Follow these steps:
In the Test section on the right, enter the following prompt, then choose the send message icon, as shown in the following screenshot.
What is the latest attempt status for player 12004?
Amazon Nova Pro generates a response using the data stored in the Redshift knowledge base.
Choose Details to see the SQL query generated and used by Amazon Nova Pro, as shown in the following screenshot.
Copy the query and enter it in query editor v2 of the Redshift knowledge base, as shown in the following screenshot.
Verify that the response generated by Amazon Nova Pro in natural language matches the data in Amazon Redshift and that the generated SQL query is also accurate.
You can try some more questions to verify the Amazon Nova Pro response, for example:
What is the lost status for player ID 12004?
How many levels did the player 12004 play?
What level did player 12004 play the most?
Show me the summary of all 14 attempts by player 12004 for level 76.
But what if the response generated by the knowledge base isn’t accurate? In those cases, you can add additional context the knowledge base can use to provide more accurate responses. For example, try asking the following question:
How many total players are there?
In this case, the response generated by the knowledge base doesn’t match the actual player count in Amazon Redshift. The knowledge base reported about 13,589 players and generated the following query to get the player count:
SELECT COUNT(DISTINCT player_id) AS "Number of Players" FROM games.game_attempts;
The following screenshot shows this question and result.
The knowledge base should have used the players table in Amazon Redshift to find the unique players. The correct response is 10,816 players.
To help the knowledge base, add a curated query for it to use the players table instead of the attempts table to find the total player count. Follow these steps:
On the Amazon Bedrock console in the left navigation pane, choose Knowledge Bases and select your Redshift Knowledge Base.
Choose your query engine and choose Edit, as shown in the following screenshot.
Expand the Curated queries section and enter the following:
In the Questions field, enter How many total players are there?.
In the Equivalent SQL query field, enter SELECT count(*) FROM “dev”,“games”,“players”;.
Choose Submit, as shown in the following screenshot.
Navigate back to your knowledge base and query engine. Choose Sync to sync the knowledge base. This starts the metadata ingestion process so that data can be retrieved. The metadata allows Amazon Bedrock Knowledge Bases to translate user prompts into a query for the connected database. Refer to Sync your structured data store with your Amazon Bedrock knowledge base for more details.
Return to Test Knowledge Base with Amazon Nova Pro and repeat the question about how many total players there are, as shown in the following screenshot. Now, the response generated by the knowledge base matches the data in player table in Amazon Redshift, and the query generated by the knowledge base uses the curated query with the player table instead of the attempts table to determine the player count.
Cleanup
For the walkthrough section, we used serverless services, and your cost will be based on your usage of these services. If you’re using provisioned Amazon Redshift as a knowledge base, follow these steps to stop incurring charges:
In this post, we discussed how you can use Amazon Redshift as a knowledge base to provide additional context to your LLM. We identified best practices and explained how you can improve the accuracy of responses from the knowledge base by following these best practices.
About the authors
Narendra Gupta
Narendra is a Specialist Solutions Architect at AWS, helping customers on their cloud journey with a focus on AWS analytics services. Outside of work, Narendra enjoys learning new technologies, watching movies, and visiting new places.
For provisioned clusters, Amazon Redshift periodically performs maintenance to apply fixes, enhancements, and new features to your cluster. Amazon Redshift assigns a 30-minute maintenance window. To prioritize business continuity and to align with your operational needs, this maintenance window is fully customizable, either programmatically or through the AWS Management Console for Amazon Redshift. For more information, see Managing clusters using the console.
A robust notification system is available to inform you about maintenance activities on your Amazon Redshift clusters to help you plan effectively and maintain communication with your users about scheduled system updates. Using the Amazon Redshift integration with Amazon Simple Notification Service (Amazon SNS), you can enable notifications of an upcoming maintenance events by creating an Amazon Redshift event notification subscription.
Customizing your provisioned cluster maintenance events
Amazon Redshift provides several ways to control how AWS maintains your provisioned clusters. The following are the primary customization options available:
Modifying the schedule for upcoming maintenance events: You can control when we deploy updates to your clusters.
Deferring upcoming maintenance: You can defer non-mandatory maintenance updates for a defined period of time.
Choosing a maintenance track to optimize performance: You can choose whether your cluster runs the most recently released version or the version released prior to the most recently released version.
Receiving notifications of upcoming maintenance: You can set up notifications for upcoming maintenance events scheduled for your clusters.
There is no set maintenance window for Amazon Redshift Serverless. When a new version becomes available for a workgroup’s chosen track, Amazon Redshift Serverless typically applies the update during an idle period as long as there is no pending track update request. If the workgroup doesn’t experience an idle period within 14 days, Redshift Serverless forces the version update.
Modifying the schedule for upcoming maintenance events
If a maintenance event is scheduled for a given week, it starts during the assigned 30-minute maintenance window. While Amazon Redshift is performing maintenance, it terminates queries or other operations that are in progress. If there are no maintenance tasks to perform during the scheduled maintenance window, your cluster continues to operate normally until the next scheduled maintenance window.
You can change the scheduled maintenance window by modifying the cluster, either programmatically or by using the Amazon Redshift console. You can find the maintenance window and set the day and time it occurs for the cluster under the Maintenance tab.
Deferring upcoming maintenance
Amazon Redshift provides additional control over cluster maintenance by deferring upcoming maintenance for up to 45 days. This feature is invaluable when you need uninterrupted cluster access during critical business periods. For instance, if your cluster’s maintenance window is set to Thursday from 5:30–6:00 UTC, and you need to have nonstop access to your cluster for the next 2 weeks, you can defer maintenance to a date 2 weeks from now. We don’t perform maintenance on your cluster during a specified deferment.
While standard maintenance can be deferred, mandatory updates—such as critical security patches, which typically occur at most annually, or hardware updates—must proceed as required. In these cases, Amazon Redshift notifies you through both the console and your Amazon SNS subscription, marking these as pending events, and implements these changes regardless of deferral settings to maintain the security and reliability of your infrastructure.
While performing deferred maintenance on Amazon Redshift clusters with Amazon Redshift data sharing configured, maintaining version compatibility between producer and consumer clusters is crucial for supporting reliable data sharing. As a best practice, you should keep producer and consumer clusters within two versions of each other to minimize potential compatibility issues. For instance, if a producer cluster is running version P195, consumer clusters should be between P193 and P197. To support effective version management, you can also use notification systems that provide timely alerts about planned cluster patching, enabling proactive version alignment and reducing the risk of potential data sharing disruptions.
Choosing a maintenance track to optimize cluster performance
Amazon Redshift offers two maintenance tracks that provide you control over how and when cluster version updates are applied, helping to ensure optimal performance while minimizing business disruption. The Currenttrack automatically applies updates during your scheduled maintenance window, keeping your cluster on the latest version with the newest features and improvements. For organizations requiring additional validation time, the Trailingtrack delays version updates after release, allowing thorough testing of your workloads in development environments before production deployment.
Using the Amazon Redshift Trailing track in your production environment, and the Current track in your testing and development environment, gives you additional diligence and time to evaluate the latest release. This approach enables you to validate version updates thoroughly before they reach your production environment. Additionally, scheduling maintenance windows during off-peak hours and establishing a communication protocol to notify stakeholders about upcoming maintenance events minimizes potential impact on production because of maintenance events.
Receiving notifications of upcoming maintenance events
By setting up an Amazon SNS email notification, you can receive real-time updates about your cluster’s maintenance details directly in your inbox. See Amazon Redshift provisioned cluster event notifications for maintenance event categories along with event ID, severity, and notification descriptions.
Set up Amazon Redshift event notifications using Amazon SNS
This section demonstrates how you can set up Amazon SNS notifications for Amazon Redshift maintenance events. For setting up the event notification, we showcase the following two options in this post:
We assume you have already deployed an Amazon Redshift provisioned cluster. For more information on creating a provisioned cluster, see Creating a cluster.
In the left navigation pane, choose Amazon Redshift and then choose Events.
Select Event Subscriptions and then choose Create event subscription.
On the Create event subscription page, enter the following information:
In the Subscription details section, under Event subscription name, enter a name for the event.
In the Subscription type section, under Source type, select Cluster.
For Cluster, choose Select clusters, and then select your cluster IDs.
For Categories, select your categories.
For Severity, select either Error or Info, Error.
In the Subscription actions section, select an existing topic or choose Create a new Amazon SNS topic, enter a topic name and then choose Create topic. See create a topic for information about creating a new topic using the Amazon SNS console.
Choose Create event subscription.
Under the Event subscriptions section, you can now see the new event subscription.
In the Amazon SNS console, choose Topics and select the topic you configured in Amazon Redshift events in the previous step.
Choose Create Subscription, under Protocol choose Email and enter a valid email address and choose Create Subscription. You can also select additional protocols based on your preference.
Choose Pending Subscription and choose Request Confirmation. After the confirmation email is received, choose the Confirm Subscription link in the email.
These event notifications work at the AWS account level.
Using an AWS CloudFormation stack
In this section, you build and configure event notifications on existing Amazon Redshift clusters using an AWS CloudFormation stack:
Choose Create Stack and select With new resources (standard).
Under Specify template, select Upload a template file.
Select Choose file and upload the CloudFormation template you downloaded in Step 1 and choose Next.
In Stack Name, enter AmazonRedshift-EventSubscription.
Enter the Parameters as follows:
For ClusterIdentifier, enter the value for your Amazon Redshift cluster. This can be found by navigating to the Amazon Redshift console and locating the cluster identifier. To subscribe for all clusters in your account, leave this field blank.
For EmailAddress, enter a valid email address.
For EventSubscriptionName, enter the value for your event subscription. (for example, Redshift-event-subscription).
For MonitorAllClusters, select from dropdown:
Select False if you entered a cluster identifier (subscribing to notification for one cluster)
Select True if you want to monitor all clusters.
For Severity Level, select from dropdown:
Select Error if you want to subscribe to error notifications only.
Select Info if you want to subscribe to both error and information notifications.
Choose Next, review the final page, and choose Submit.
You will receive an email with subject AWS Notification – Subscription Confirmation. Choose Confirm subscription.
In this section, we show you some examples of notification emails sent through Amazon SNS based on the configuration:
Database Update notification:
Amazon Redshift regularly releases cluster versions. The Scheduled Database Update notification, shown in the following screenshot, is sent before an upcoming Amazon Redshift patch version upgrade.
System Update notification:
AWS performs regular updates to the underlying hardware and operating system of Amazon Redshift clusters, including security patches and performance improvements. The Scheduled System Update notification, shown in the following screenshot, is sent before scheduled hardware and OS updates.
If you’re running your non-production clusters on the Current track and production services on the Trailing track, you can receive notifications when your non-production clusters undergo patching, so you can proactively test the release before it goes to your production servers. You can promptly report issues with the update through the AWS Support Center console. If the reported issues are still present when your production clusters are scheduled for the same patch in the Trailing track, you can defer maintenance until the concerns are resolved for stability. To learn how to change tracks for an Amazon Redshift cluster, see Switching between tracks.
Stay informed about version updates using RSS feeds
To stay informed about the latest cluster versions released for Amazon Redshift, you can also use the RSS feed of the Cluster versions for Amazon Redshift page in your monitoring toolkit. Unlike real-time cluster notifications, this feed serves as your window into documentation updates, giving you early updates into published features and best practices. While it won’t alert you about immediate cluster maintenance or security patches, you’ll be notified whenever Amazon updates their cluster management documentation. By adding this RSS feed to your preferred reader, you’re subscribing to a continuous stream of AWS documentation updates, helping you to maintain a proactive rather than reactive approach to your data warehouse management.
Setting up an RSS feed for your Amazon Redshift documentation is straightforward and offers multiple options to suit your workflow preferences. The key is to first choose your preferred RSS reader, such as Slack or Microsoft Outlook, or your preferred web-based RSS feed reader. To start receiving notifications about AWS documentation updates, add the RSS feed URL to the reader to start receiving updates. After setup, you will receive notifications whenever the Amazon Redshift cluster management documentation is updated, helping to keep you informed about new features and best practices.
You can also see the updates directly on the Cluster versions for Amazon Redshift page to stay informed whenever a new version has been released and before it’s scheduled to be released to your cluster.
Cleanup
If you don’t need the Amazon SNS notification created for this post, delete the Amazon SNS topics from the Amazon SNS console to avoid incurring future charges. If you have configured the notification using AWS CloudFormation, delete the stack to delete related configurations. See Amazon SNS Pricing for pricing information for the service.
Conclusion
In this post, you learned how to configure maintenance event notifications for Amazon Redshift provisioned clusters using Amazon SNS. We also explained the details of Amazon Redshift maintenance activities, including how to manage the schedule for upcoming maintenance by using Amazon Redshift maintenance tracks to optimize cluster performance, and using RSS feeds to receive real-time updates about critical cluster information.Upgrading your Amazon Redshift clusters to the suggested maintenance track is critical for optimizing cluster performance and to help to ensure that the latest fixes, security patches and enhancements are applied to your clusters. Seamless integration with the Amazon SNS notification system helps ensure that you’re informed of maintenance events ahead of time, so that you can prepare for them. This proactive approach helps you to plan effectively and maintain communication with your users about scheduled system updates.
Phones running Linux are ubiquitous these days and it has been that way
since Android started working toward dominance in the smartphone market.
Unfortunately, Android has slowly increased its freedom-unfriendliness and
has become something of a privacy nightmare. In a talk entitled “We need
an open-source phone OS” at Open
Source Summit Japan 2025, Luca Weiss described the smartphone landscape
and gave an overview of postmarketOS as an alternative Linux
operating system for mobile handsets.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.

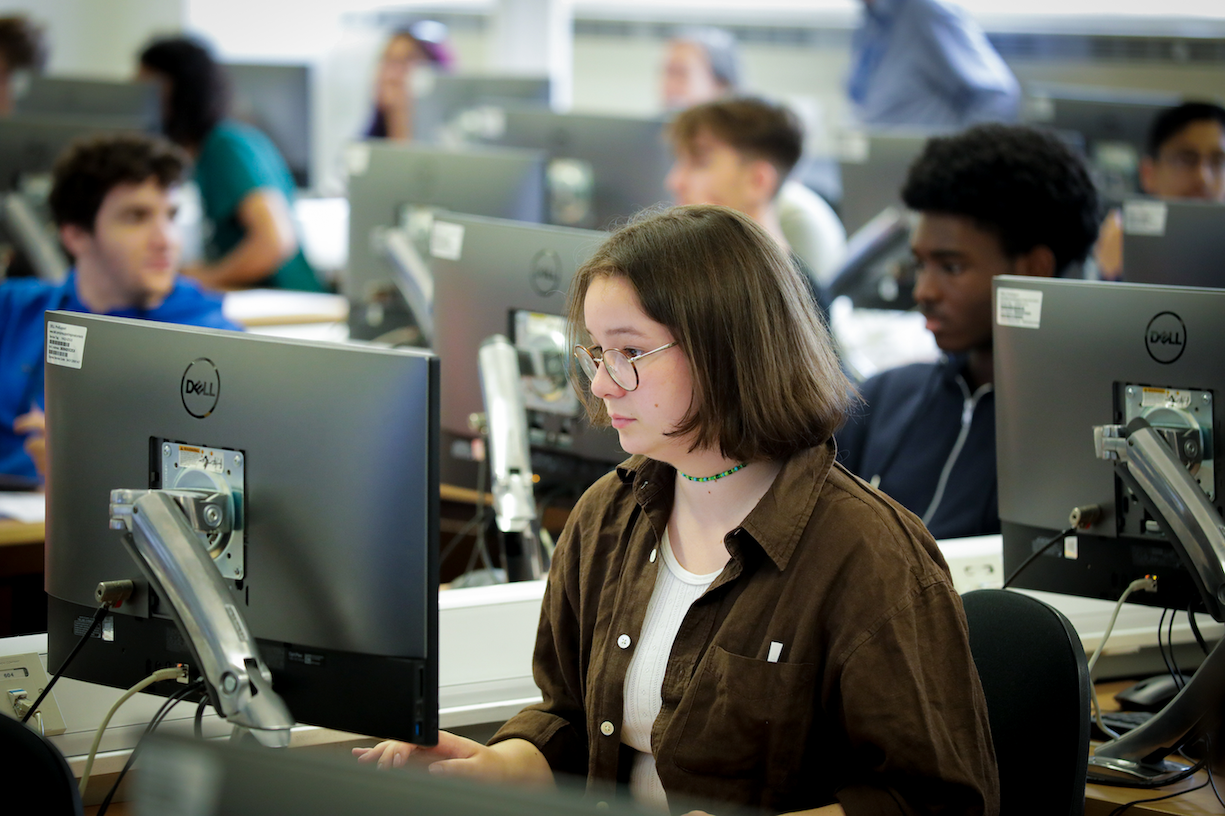

 ISP-Regional traffic dominates in total traffic volume. This region has the largest data center footprint behind it, with connectivity to internet exchanges (IX) such as