Валутата на президента

Post Syndicated from Емилия Милчева original https://www.toest.bg/valutata-na-prezidenta/

Валутата на президента

По-малко от 17 месеца остават до следващите президентски избори, а Румен Радев все още няма яснота за своето политическо бъдеще, след като излезе от „Дондуков“ 2. Тази несигурност го прави уязвим и податлив на инициативи като референдума за еврото. Внушена от външни и вътрешни съветници, тя не ентусиазира особено народа, към когото уж е насочена. След като отправи вечерно обръщение на 9 май и един блед коментар, президентът изчезна от публичното пространство. И проговори в деня, в който отпътува за чужбина, за което се разбра случайно. Радев заминава със съпругата си в Япония, където ще остане до 21 май за участие в Деня на България на Световното изложение ЕКСПО 2025. 

През тези осем дни управляващи и опозиция сключиха пакт за примирие и се обединиха в името на еврозоната, а президентското искане за референдум изобщо не стигна до пленарната зала. Държавният глава не направи обръщение в парламента, а предпочете да коментира от летището, без да допусне журналистически въпроси. Съобщи, че ще сезира Конституционния съд (КС) заради отказа на парламента да разгледа предложението му за всенародно допитване за или против въвеждане на еврото през 2026 г. – както го посъветваха и от „Възраждане“.

В изявлението си Радев повтори опасността от инфлация, каквато имало в други държави, въвели единната европейска валута, приписа си заслугите за избуялите дебати, придържайки се към наратива за „eлитите“ и „народа“, станал негова запазена марка.

Моето предложение вече дава резултати. Най-сетне започнаха дебати за реалната ни готовност да приемем еврото следващата година. Най-сетне чухме от устатата на господата Пеевски и Борисов думите „цени“ и „нужда от контрол“. Твърде късно и под натиск. 

Председателката на 51-вото Народно събрание Наталия Киселова му върна искането за референдум като недопустимо, а в писмена позиция от Президентството определиха действието като „отдалечаване от демокрацията и законността“.

Правните основания за решението на Киселова са следните:

Предложението не беше разпределено [за разглеждане – б.а.], тъй като не е в съответствие с чл. 5, ал. 4 във връзка с чл. 4, ал. 3 и чл. 85, ал. 3 от Конституцията на Република България, чл. 140, параграфи 1 и 2 от Договора за функционирането на Европейския съюз, чл. 3 от Договора за присъединяване на Република България към Европейския съюз, чл. 5 от Акта относно условията за присъединяване на Република България и Румъния и промените в Учредителните договори и чл. 9, ал. 4 от Закона за пряко участие на гражданите в държавната власт и местното самоуправление.

Предложението на държавния глава и мотивите към него не са съобразени с мотивите и диспозитива на Решение №3 на Конституционния съд от 2024 г. по к.д. №13/2023 г.

Наистина КС вече се произнесе: референдум за отлагане на приемането на еврото нe може да има. Партия „Възраждане“ предложи всенародно допитване с въпрос „Съгласни ли сте българският лев да бъде единствена официална валута в България до 2043 г.?“, но парламентът го отхвърли. 

Причината е, че чл. 9, ал. 4 от Закона за пряко участие на гражданите в държавната власт и местното самоуправление забранява с референдум да се решават въпроси, уредени в сключени от България международни договори. Плебисцит е възможен преди ратификацията им – за еврото е бил допустим преди 11 май 2005 г., когато парламентът ратифицира Договора за присъединяване към ЕС. 

Заради решението на КС от „Възраждане“ струпаха животински изпражнения пред институцията, изгориха бали сено и дори подпалиха автомобил. Но освен тези провокации, недопускането на референдума не отприщи по-силни народни вълнения.

Иронично или не, сега именно президентското искане доведе до нещо рядко – обединение на управляващи и опозиция, за да препотвърдят еврозоната като стратегическа цел. Направиха го и синдикати, бизнес, представители на академичната общност. В декларация преподаватели по право от български университети се обявиха срещу референдума. По Нова телевизия доц. Христо Христев от Софийския университет обясни позицията им:

… евентуалното свикване на референдума би означавало суспендиране на установения конституционен модел за вземане на решения в основни институции на България.

Всъщност след изявлението на Радев наистина започна същинската информационна кампания за еврото, при това три седмици преди Европейската комисия и Европейската централна банка (ЕЦБ) да излязат с конвергентните доклади. Индикативната дата за тях е 4 юни, а правителството е препотвърдило искането си, както се разбра от еврокомисаря по икономиката Валдис Домбровскис:

Не мога да коментирам вътрешни работи, но проведохме разговор с министъра на финансите Петкова заедно с ЕЦБ и президента на Еврогрупата. Посланието на министър Петкова беше много ясно – българското правителство заедно с БНБ подадоха искане за конвергентен доклад. И те се придържат към искането си. В отговор Комисията и ЕЦБ продължават да работят върху изготвянето му и се предвижда работата по него да приключи в началото на юни.

Партии vs. Румен Радев

Защо преподавателката по конституционно право Наталия Киселова не допусна искането за референдум в пленарната зала? Преди това авторитетни юристи като проф. Екатерина Михайлова предложиха същото. „Ако предложението за референдум бъде върнато като недопустимо от Народното събрание, президентът няма какво да изпрати на КС“, обясни по Нова телевизия проф. Михайлова. 

Лидерът на „Възраждане“ Костадин Костадинов публично предложи правна помощ на екипа на президента, за да поиска тълкувателно решение от КС за отказа на Киселова. Което Радев и направи.

Ако неговият екип има проблеми с написването на подобно искане до Конституционния съд, и ние, и всеки един от не особено добрите юристи в страната може да помогне.

Това иронично-подигравателно отношение от съмишленик към съмишленик е доказателство, че на Радев вече гледат като на „колега“, бъдещ играч на партийния терен. Парадоксално – човекът, който винаги е назидавал партиите за тяхната неефективност, унижавал е парламентарната република, обмисля партиен проект. Само че така и не събира смелост да го направи. 

С действията си обаче президентът предизвика ситуационно обединение на политически сили срещу себе си. Изключение правят „Величие“, които бранят позициите му и даже вредния за българските национални интереси договор с „Боташ“, и „Възраждане“, но те ревнуват, понеже са убедени, че имат патент върху битката срещу еврото. 

ГЕРБ–СДС, ПП–ДБ, двете ДПС-та и дори БСП обявиха, че ако искането за референдум влезе в пленарната зала, ще гласуват против. „Има такъв народ“ – партията, която първа подкрепи Радев за втори мандат, е за референдум (предвид своя генезис). Но както обясни Тошко Йорданов, в случай че има такъв, ще агитират за еврото. 

ГЕРБ–СДС и „Демократична България“ видяха откровен саботаж в искането на президента. Според лидера на ГЕРБ Бойко Борисов президентът е решил в последния момент „да бламира България и да не можем да влезем в еврозоната“: 

Никой не казва, че е срещу еврозоната, а започват да определят някакви дати – сиреч да излъжат избирателите си. Просто него го е яд, че правителството и парламентът се справиха и си изпълниха критериите. Единственият начин да бъдем спрени от еврозоната е да покажем нестабилност.

Съпредседателят на „Да, България“ (от обединението ДБ) Ивайло Мирчев определи хода на президента като „част от неговия политически проект“.

Безпрецедентното изявление на президента Румен Радев за референдум за еврото е саботаж срещу влизането ни в еврозоната, няма по-грубо и безотговорно действие срещу националния интерес.

Съпредседателят на „Продължаваме промяната“ Асен Василев нарече инициативата на Радев „провокация“.

Последните няколко месеца върви една изключително агресивна дезинформационна кампания, която да плаши хората, че ще им вземат парите, влоговете… Чухте, даже вицепрезидентът Йотова каза, че това е лъжа. Но на тази лъжа последните проучвания показаха, че 40% от българите са ѝ повярвали.

Лидерът на ДПС – Ново начало Делян Пеевски смята, че целта на президента е да всее раздор и противопоставяне в обществото с предложението си.

Изказването на Радев от 19 часа в Деня на Европа е толкова несъстоятелно, че заради институцията, не заради персоната с неосъществени мераци, трябва снизходително да се престорим, че не се е случило.

„Потъпкват демокрацията…“

За да се подгрява темата, публични говорители, свързвани с Радев, излизат с рефрена, че е потъпкана демокрацията с недопускането на референдума. Самият държавен глава даде тон за този разказ в единствения коментар, преди да замине за Япония. Но същността на искането му е да спъне България по пътя към еврото, опаковано като допитване до народа.

Инициативата на президента ще всее допълнително недоверие в разделеното българското общество, силно облъчвано с дезинформационни кампании и руска пропаганда. Но дали ще изцеди обществено недоволство, което да го направи народен трибун, по-голям от проруските евроскептици Костадинов, Михайлов и Василев, взети заедно? Радев започна втория си мандат с 58,5% доверие и с недоверие от 32,1% и макар последни проучвания да показват лек спад – 47% доверие срещу 31% недоверие, той остава единственият с позитивен нетен рейтинг. 

В първия си мандат Румен Радев печелеше симпатии с позиционирането си срещу статуквото и беше възприеман от гражданите като символ на борбата срещу задкулисието и корупцията, а също и за „морален съдник за правителството“, както го определи проф. Милена Стефанова. Забрави се неизпълненото му обещание да предложи законопроект за промени в Конституцията.

Онова, което ще се запомни от неприключилия втори мандат, е противопоставянето му по две ключови теми, знакови за европейската принадлежност и европейска интеграция на България: подкрепа и помощ за Украйна и единната европейска валута. Наклонът към руския агресор, демонстриран от Радев и от служебните му правителства, поставиха България редом до Орбанова Унгария в ЕС и нанесоха репутационни щети. Към тези „заслуги“ се прибави и вредният 13-годишен договор с турската компания „Боташ“, сключен от служебен кабинет на президента. Тази договорка влошава финансовото състояние на „Булгаргаз“ – за 2024 г. компанията е на загуба с 280 млн. лв., а към 31 март 2025 г. дължи на „Боташ“ 250 млн. лв.

По контракта „Булгаргаз“ плаща около един милион лева дневно на „Боташ“ за капацитет, който не ползва, защото цената на газа ще е твърде висока. Почвата за сключването му подготвиха разговори на Радев с турския президент Реджеп Тайип Ердоган през есента на 2022 г. Скоро след това се подписа и споразумението за запазен капацитет за внос на 1,85 млрд. куб.м годишно на турските терминали, а най-скандалното е, че не може да бъде развален, освен ако не се плати цялата сума от над 4 млрд. лв. 

Сметката може да достигне и 6 милиарда, обясни в парламента енергийният министър Жечо Станков, извикан на изслушване от депутатите. Чуха се отново факти, известни още от заседания на временната парламентарна комисия от миналата година, свикана, за да ги изясни – например че договорът не е бил представен на министерствата, през които е минал за съгласуване, но има одобрението на Министерския съвет.

Именно във втория мандат пролича най-силно властолюбието на Радев чрез извършените от служебните му кабинети поголовни смени на ръководствата на служби, в държавните дружества и по институциите под контрола на изпълнителната власт. По Българското национално радио проф. Стефанова заяви, че президентът не може да бъде алтернатива на управлението, както не може да бъде и опозиция.

Нормалните президенти някак си излъчват кабинет и не се бъркат в работата му, докато Радев много обичаше да се възпалява като глава на правителството, само дето не можеше да се окичи и с това да е премиер.

Тревогите – зад гърба, страховете – у хората

Фискалният съвет се зае да разбива слуховете за висока инфлация, настъпила в държави, приели еврото. „Този въпрос, който хвърли в голяма тревога демократичната общност в страната, вече е зад гърба ни“, заяви премиерът Росен Желязков след решението на Киселова. 

Дали? 

„Възраждане“ реши да рестартира битките си срещу еврото с призив към граждани да се съберат пред НДК на 16 май, където в зала 1 ще се обсъждат „превантивни мерки срещу насилственото вкарване на България в еврозоната“.

Преди да отлети за албанската столица Тирана за Срещата на върха на Европейската политическа общност, премиерът благодари на онези 171 народни представители, подкрепили декларацията, подписана от него и от управителя на БНБ Димитър Радев, потвърждаваща решителността на България да приеме еврото от 1 януари 2026 г. Желязков благодари и на бившите премиери Иван Костов и Бойко Борисов и даде обещания:

Отиваме към увеличаване на конкурентоспособността на българската икономика. Когато получим положителната оценка на доклада, ще излезем с редица мерки, за да се изпълнят принципите за въвеждане на еврото – защита на потребителите, информираност и ефективност; ще предложим промени, които трябва да внесат успокоение в българското общество; ще въведем контролни механизми, които ще дадат възможност ефективно да се спазва законодателството и да не се допускат спекула и спекулация.

Страховете на хората обаче не са зад гърба на политиците, съвсем реални са – те са валутата на популизма. Румен Радев си отваря сметка именно в тази валута.

Ivanti Endpoint Manager Mobile exploit chain exploited in the wild

Post Syndicated from Ryan Emmons original https://blog.rapid7.com/2025/05/16/etr-ivanti-epmm-exploit-chain-exploited-in-the-wild/

Ivanti Endpoint Manager Mobile exploit chain exploited in the wild

On May 13, 2025, Ivanti disclosed an exploited in the wild exploit chain, comprising of two new vulnerabilities affecting Ivanti Endpoint Manager Mobile (EPMM): CVE-2025-4427 and CVE-2025-4428. Ivanti EPMM is an enterprise-focused software suite for IT teams to manage mobile devices, applications, and content.

CVE-2025-4427 is an authentication bypass vulnerability with a CVSS rating of 5.3 (Medium). CVE-2025-4428 is an authenticated remote code execution (RCE) vulnerability with a CVSS rating of 7.2 (High). By chaining the medium-severity authentication bypass (CVE-2025-4427), an unauthenticated attacker can reach a web API endpoint to inject server-side template patterns and exploit the high-severity vulnerability (CVE-2025-4428), thus achieving unauthenticated remote code execution. Therefore, while neither vulnerability has been rated as critical, when combined together, the impact of the exploit chain is critical, i.e. unauthenticate RCE.

The vulnerabilities were reported to the vendor by CERT-EU, the European Union’s Cybersecurity Service for the Union institutions, bodies, offices and agencies. The vendor has disclosed that this exploit chain has been exploited in the wild to a limited degree. Notably, this product was previously targeted by an unknown threat actor against the Norwegian Security and Service Organization (DSS) in 2023.

On May 15, 2025, a technical analysis and accompanying proof-of-concept exploit was published publicly. With public exploit code now available, the risk of broad exploitation in the wild has greatly increased.

Mitigation guidance

The vendor has provided patches for affected versions of EPMM. Customers are advised to follow the vendor guidance, and remediate this vulnerability by upgrading to a fixed version on an emergency basis, without waiting for a regular patch cycle to occur.

The following list outlines the affected supported EPMM versions, and their respective fixes:

  • Version 11.12.0.4 and prior is fixed in version 11.12.0.5
  • Version 12.3.0.1 and prior is fixed in version 12.3.0.2
  • Version 12.4.0.1 and prior is fixed in version 12.4.0.2
  • Version 12.5.0.0 and prior is fixed in version 12.5.0.1

For the latest mitigation guidance, please refer to the vendor advisory.

Rapid7 customers

InsightVM and Nexpose customers can assess exposure to CVE-2025-4427 and CVE-2025-4428 with unauthenticated checks expected to be available in today’s (May 16) content release.

Ready, set, Scratch: A beginner’s guide to creative coding

Post Syndicated from Mark Calleja original https://www.raspberrypi.org/blog/ready-set-scratch-a-beginners-guide-to-creative-coding/

What is Scratch?

Scratch is a free, beginner-friendly coding platform that allows young people to create animations, games, and interactive stories using simple visual blocks. Scratch removes some of the complexity of coding by replacing syntax-heavy programming languages with intuitive drag-and-drop blocks. This lets creativity take centre stage and makes it the perfect first step for young coders.

Two young people smiling whilst working on their laptop with an adult mentor by their side.

Why Scratch is the ideal starting point

Every coding journey begins with a single step. Scratch delivers this first step in a way that is playful, approachable, and empowering. Scratch immediately delivers tangible results that new coders can feel proud of by linking coding to storytelling, design, and play. It also cultivates curiosity, confidence, and resilience — qualities crucial to long-term success in both coding and problem solving.

Most importantly, Scratch emphasises exploration over perfection. It invites young learners to experiment freely, troubleshoot confidently, and express themselves creatively without fear of making mistakes. This exploratory mindset provides the foundation for future technical proficiency and innovation.

Get started with our free projects

Starting with structured projects helps young learners build solid coding skills while maintaining enthusiasm and enjoyment.

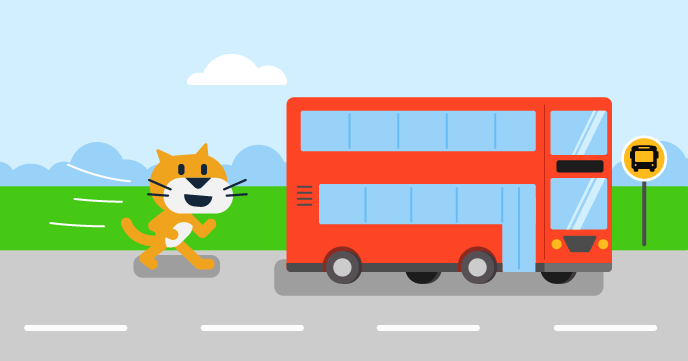
Catch the bus (animation)

In ‘Catch the bus’, coders create an animation featuring a character (called a sprite in Scratch) attempting to catch a departing bus. They learn how to sequence events, switch costumes to simulate movement, and synchronise actions to tell a simple story. This introduces fundamental storytelling and animation skills in Scratch.

What you’ll learn:

  • Timing and sequencing actions
  • Using costume changes to simulate movement
  • Creating narrative animations

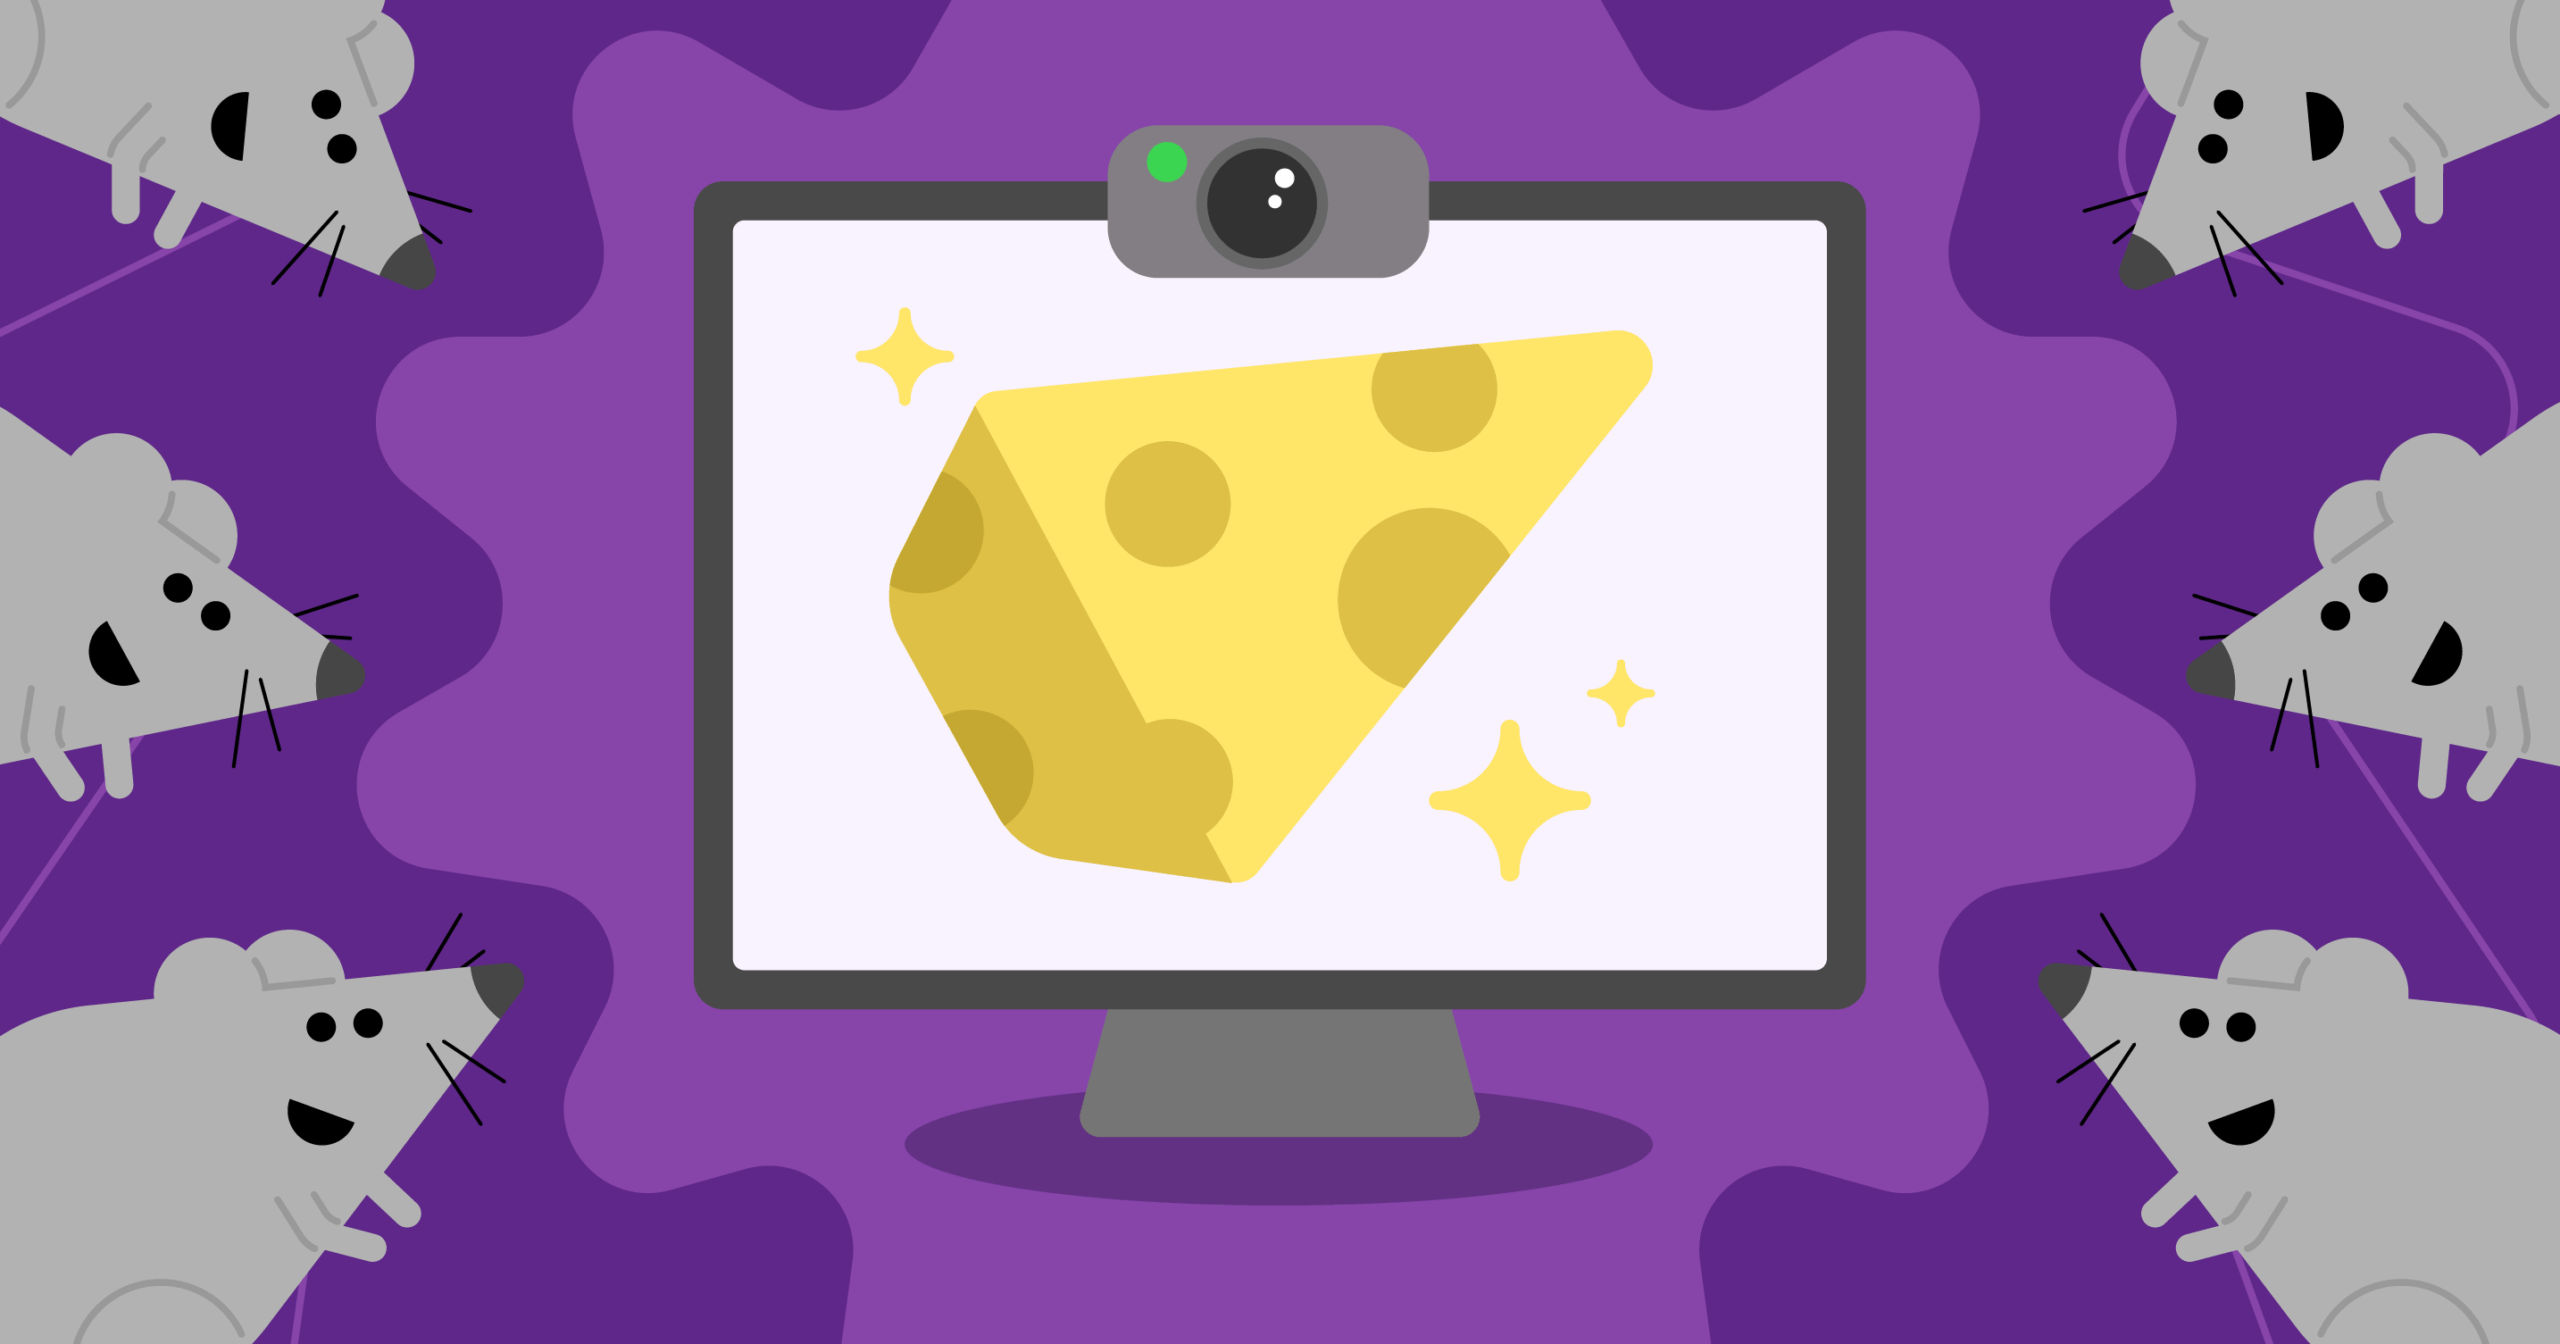
Chomp the cheese (interactive)

In ‘Chomp the cheese’, learners use facial recognition tools in Scratch Lab to build an interactive game controlled by mouth movements. Using a webcam, players physically open their mouths to “chomp” virtual cheese snacks on screen. This playful and engaging activity introduces machine learning concepts in a tangible and enjoyable way.

What you’ll learn:

  • Using facial recognition in Scratch
  • Creating interactive games with webcam input
  • Basic concepts of machine learning and interactivity

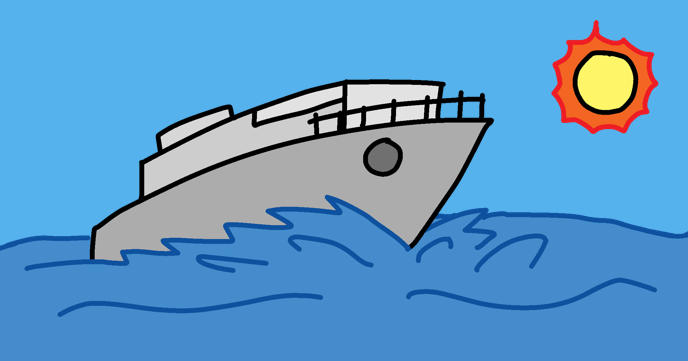
Boat race (game)

In ‘Boat race’, young coders create a game where players navigate a boat around obstacles, steering using mouse controls. They learn to handle player input, detect collisions, and define conditions for winning. This foundational game-making experience sets the stage for more complex creations in the future.

What you’ll learn:

  • Controlling sprites with mouse clicks
  • Collision detection between sprites
  • Defining goals and win conditions

“The key to sparking a lifelong interest in coding is excitement. When young people are building something they genuinely care about, they’re not worried about getting everything perfect on the first try. They’re chasing their ideas and learning as they go. Scratch creates the ideal environment for this type of messy, brilliant exploration. It provides young coders with the freedom to experiment, persevere, and express themselves — all while enjoying the process,” or so says my amazing colleague Pete Bell, Learning Manager and creator of some of our most engaging content at the Raspberry Pi Foundation. I have to say, I agree with him!

Level up and build momentum

After completing their first projects, young coders can continue to build momentum through several exciting avenues:

  • Personalise projects: Encourage learners to remix existing projects by altering characters, backgrounds, and rules. Personalisation deepens learning and fosters ownership of the coding experience.
  • Explore Python: Scratch’s block-based coding naturally leads to curiosity about text-based languages like Python, which many learners find an exciting next step.
  • Join a Code Club: Coding alongside peers transforms individual learning into a social experience. Code Clubs offer a collaborative environment where learners solve problems together, share creations, and build lasting friendships.

Encouraging personalisation, curiosity, and community involvement keeps learners motivated and engaged on their coding journey.

Children in a Code Club in India.

Conclusion

Scratch is more than just an introductory tool — it’s a creative playground that nurtures curiosity, resilience, and technical skills in equal measure. By guiding young coders through their first steps with engaging projects and supportive encouragement, you lay the foundation for a lifetime of innovation, problem-solving, and creative expression. Ready, set, Scratch! Let’s get started!

The post Ready, set, Scratch: A beginner’s guide to creative coding appeared first on Raspberry Pi Foundation.

In Memoriam: John L. Young (EFF)

Post Syndicated from corbet original https://lwn.net/Articles/1021462/

The Electronic Frontier Foundation has posted a somewhat belated memorial
for John Young
, the founder of Cryptome.

John was one of the early, under-recognized heroes of the digital
age. He not only saw the promise of digital technology to help
democratize access to information, he brought that idea into being
and nurtured it for many years. We will miss him and his
unswerving commitment to the public’s right to know.

Невидимата сексуалност на хората с увреждания в България

Post Syndicated from Светла Енчева original https://www.toest.bg/nevidimata-seksualnost-na-horata-s-uvrezhdaniya-v-bulgaria/

Невидимата сексуалност на хората с увреждания в България

Правило ли ви е впечатление, че когато се говори за деца с увреждания, нерядко се имат предвид и възрастни? Например в протестите на майки на деца с увреждания участват и родители на хора, които отдавна са навършили пълнолетие. За един родител, разбира се, детето му си е дете, независимо от възрастта. Проблемът обаче е, че доминиращото публично говорене за пълнолетни хора като за деца само защото са с различни възможности, е инфантилизиращо. Защото така се пренебрегват не само потребностите на зрели индивиди отвъд физическото им оцеляване, а и човешкото им достойнство.

„Институционализирана слепота“

Изследователите Венелин Стойчев и Надежда Денева квалифицират законодателната уредба и административните практики по отношение на хората с увреждания с думите „институционализирана слепота“. Те правят тази констатация в доклада на Центъра за независим живот „Правата на „правите“ и правата на „кривите“. Турбуленции по пътя към пълноценната лична, трудова и социална реализация на хората с увреждания в България“. В него се анализират резултатите от проучване, посветено на женствеността на жените с увреждания в България. То включва както количествена анкета, така и интервюта с жени с увреждания, техни близки, социални работници, юристи.

Интервютата хвърлят светлина върху практическите измерения на „институционализираната слепота“. Ето какво споделя социален работник например:

Имахме случай на жена със зрително увреждане, която искаше повече часове лична помощ, защото се грижи за детето си. Тогава си дадохме сметка, че Законът за личната помощ е ориентиран само около физиологичните нужди на самия човек с увреждане и няма никаква връзка с неговите социални роли. Няма как да му дадем повече часове лична помощ, за да бъде този човек с увреждане родител например. Като се замисля – май е същото и с ходенето на работа. Това е така, защото ние не очакваме хората с увреждания да са родители, роднини, граждани или да ходят на работа.

И ако държавата не очаква хората с увреждания да имат различни социални роли, толкова по-малко тя е в състояние да си представи, че те могат да имат чувство за лично пространство, усещане за интимност, нужда от любов, да не говорим за сексуални потребности.

В степента, в която човек с увреждане може да е самостоятелен, той може да се погрижи по един или друг начин и за интимните си потребности. Но колкото повече зависи от чужда помощ, толкова повече най-личната част от живота му е в ръцете на хора, които може дори да не си дават сметка за нея.

В България грижата за хора с увреждания се предоставя основно по два начина.

Ако човекът живее в домашна среда, има право на личен асистент. В общия случай тази роля поема или майката, или друг близък роднина, но понякога се възлага и на външни лица. За 2025 г. базовата заплата на личните асистенти е 1526 лв. на месец за 8-часов работен ден. На практика обаче работното време е твърде условно, защото, ако например някой не може сам да отиде до тоалетната, той може да има нужда от помощ по всяко време на денонощието.

Вторият вариант е, ако човекът с увреждане е в институция. В този случай грижите се поемат от персонала на съответната социална услуга, както се наричат подобни места.

Интимност и увреждания в домашна среда

По времето на пубертета здравите хора започват да се еманципират емоционално от родителите си, а с пълнолетието и постигането на икономическа самостоятелност вече могат да заживеят изцяло свой живот. И този живот може да е в противоречие с принципите, ценностите или желанията на родителите им.

Ако обаче сте с увреждане, в резултат на което зависите от чужда помощ, е доста вероятно да нямате шанс за еманципация. Интимните ви нужди може да останат изцяло незабелязани покрай полагането на физически грижи и търчането по институции, пред които отново и отново трябва да се доказва здравословното ви състояние. Особено ако за хората, които се грижат за вас, сексуалните теми са нещо срамно.

Не вярвах, че някога ще целуна момче, но се упражнявах – целувах си ръката, дланта, пробвах как е с език. Целувах манекените от списанията. […] Момичешки глупости, по цял ден бях сама вкъщи и не знаех какво да правя…

Това са думи на респондентка в изследването на Венелин Стойчев и Надежда Денева. Друга споделя, че не е знаела какво е менструация, когато е дошъл първият ѝ цикъл, и е помислила, че става дума за влошаване на състоянието ѝ. Такъв опит имат и здрави жени с по-консервативни родители, за които подобни теми са табу. Една от интервюираните обаче разказва за своя приятелка, която едва на 50-тина годишна възраст открила мастурбацията – нещо, което повечето здрави деца започват да практикуват от ранна възраст:

И тя ми казва, че ще ми издаде някаква много важна тайна, но да не казвам на никого. И се чудя каква ли е пък тази тайна, дето аз да не я знам, като сме приятелки от хиляда години и всичко си споделяме. А тя сто пъти ме накара да се закълна, че няма да казвам на никого. И след тези увещания накрая ми сподели, че ѝ е хубаво, когато се пипа там долу. Викам ѝ: „Здрасти ма, това се казва мастурбация, на всички ни е хубаво!“ А нея я е срам, че майка ѝ ѝ е личен асистент и ще разбере. И на мен главата ми не може да го проумее – да станеш на петдесет години, за да откриеш мастурбацията и да те е срам от майка ти… В кой век живеем…

Много хора с увреждания не получават възможност да имат интимен партньор или сексуални контакти – не защото физически или умствено не са способни на това, а понеже на личните им асистенти не им минава през ума, че човекът, за когото се грижат, може да има такива потребности. Или ако им минава, смятат за неприлично да се занимават с логистиката. Или пък за тях това са допълнителни ангажименти, които биха предпочели да си спестят.

Други имат пълноценен интимен живот, някои – дори семейства и деца. Но това зависи от личностния хоризонт, добрата воля и възможностите на личните им асистенти.

Но ако нуждаещият се от грижа е с хомосексуална ориентация, а личният му асистент, който в повечето случаи е майката, е с хомофобски разбирания, физическите измерения на споделената интимност се превръщат в недостижим мираж.

Когато хората с увреждания са в състояние да ползват самостоятелно интернет, това за тях е важен отдушник, възможност за социални контакти, виртуална интимност, както и за създаване на желана идентичност:

Интернет беше моето спасение. Осъзнах, че там мога да бъда каквато си искам. Не съм лъгала хората нарочно, ама никой не се представя във форумите със „Здрасти, аз съм саката и съм на количка“.

Интимност и увреждания в специализираните институции

Авторите на доклада разглеждат отношението към хората с увреждания в т.нар. домове през призмата на Мишел Фуко за дисциплинарните институции, като каквито той определя казармата, психиатрията, болницата и затвора. Участник в мониторингова програма за правата на хората с увреждания, интервюиран в изследването, оприличава клиентите на тези социални услуги на „безполови същества, не можеш да разбереш кой е мъж и кой е жена – всичките са остригани, всичките са с едни дълги нощници и бродят като призраци из двора“.

По отношение на живеещите в такива „домове“ думата „потребител“ съдържа особен цинизъм. Защото отношението към един потребител е свързано със стремеж към удовлетворяването на личните му потребности, докато в институциите хората с увреждания са сведени до физиологията си. Експерт в областта на хората с увреждания обяснява манталитета на персонала на домовете така:

Това са едни не лоши, но семпли женици от село, които смятат, че са си свършили работата, ако потребителите им са нахранени, ако са измити, ако им е изчистено. Те просто не могат да видят повече от това. Все едно им е дали се грижат за наранена сърничка, или за човек с увреждане.

В такава среда не може да се очаква уважение към човешката неприкосновеност или допускане, че един човек с увреждане може да има нужда от лично пространство или да изпитва срам. Интервюираният експерт описва случай на момиче с детска церебрална парализа, което не може да говори. Хора от персонала коментират, че момичето става агресивно, когато му сменят памперса, без да отчитат факта, че те правят това пред погледа на момчетата в дома:

Смъкват ѝ гащите, всичко ѝ се вижда от другите младежи, половите ѝ… Беше толкова дивашко, но никой дори и не си помисляше, че това може да е някакъв проблем… Третират ги като малки деца – ако имат памперс, значи ги смятаме за бебетата, не очакваме, че вече разбират, че вече се срамуват…

По същия начин персоналът на тези институции не допуска, че обитателите – дори тогава, когато са в интимна връзка или в брак – могат да имат потребност от любов и личен живот. Интервюираният експерт на мониторингова програма разказва за случай в един смесен дом, тоест за хора от двата пола. В него имало мъж и жена, които са заедно. Но служителите решили да разделят потребителите с психически увреждания от тези с физически. И понеже мъжът бил с лека умствена изоставеност, разделили влюбените насила:

Ние бяхме на посещение и мъжът се оказа избягал. И питаме персонала къде е, а те умират от смях. Оказа се, че той просто всеки ден тръгва пеша по пътя към съседния град, където е жена му. Питам какво го правят, щом знаят къде е, разрешават ли им да се видят. А те се смеят: „Да бе, ще му разрешим! Намираме го по пътя и го връщаме обратно тук, разбира се.“

В домовете, които не са смесени, хомосексуалните отношения са обичайна практика. Както казва един от респондентите, социален работник:

Ти може и да не си лесбийка, но само това е материалът, дето викаше Бойко [Борисов – б.а.]. То е като в казармата, като в затвора – нямаш избор.

В институциите за хора с увреждания сексуалната експлоатация не е изключение. В доклада се описва и случай, в който управителката на едно защитено жилище фактически си присвоява бебе, чиято майка е млада жена с лека форма на умствено увреждане, а бащата е под частично запрещение.

Как е в други страни

Когато на хората с увреждания се гледа като на човешки същества, се създават условия, в които те в максимална степен да могат да имат нормален личен живот, сексуални контакти, да създават семейства.

В някои западноевропейски държави социалното осигуряване покрива сексуални услуги за хора, които поради естеството на уврежданията си трудно могат да си намерят интимен партньор. И има хора, специализирани в предоставянето на такива услуги.

Никога не съм си представяла, че някой ден ще правя секс. Камо ли че ще се омъжа, ще имам съпруг и дете. Никога, беше немислимо отвъд въображението…

Интервюираната жена, която казва това, все пък създава семейство. Но не в България, а във Великобритания. Ходи и на работа. И споделя:

В Англия не мога да им обясня какво е това ТЕЛК, как това е по-важно от паспорта ми. Колегите ми там просто недоумяват…

Друга респондентка има приятелка в чужбина, омъжена и с три деца. Както и личен асистент, който я подготвя за секс с мъжа ѝ и помага в отглеждането на децата.

Възприемането на хората с увреждания като равноценни не би могло да се прилага само от институциите, без да се споделя и от достатъчно членове на обществото.

„Пролетно тайнство“ е испански филм за млада жена с консервативно възпитание, която решава да предоставя сексуални услуги на мъж с тежко увреждане, който е почти неподвижен. Прави го не за парите, а от емпатия – защото общуването с мъжа ѝ помага да си даде сметка какво е да имаш потребност, която не си в състояние да задоволиш.

И ако този филм е художествена измислица, германската обществена медия WDR представя в документална поредица как хора с различни увреждания търсят любов (първа, втора, трета и четвърта част). Помагат им и родителите, и социалната система, и цялата публична среда – всичко заедно прави възможно те да имат пълноценен живот – и социален, и интимен.   

А в България любовните и сексуалните потребности на хората с увреждания, нуждата им от интимност и от лично пространство ще бъдат „десетата дупка на кавала“ дотогава, докато продължават да бъдат възприемани като пасивни обекти на грижа. А не като личности с човешко достойнство.

Continue to take control over your code with Amazon Q Developer’s new context features

Post Syndicated from Eva Knight original https://aws.amazon.com/blogs/devops/continue-to-take-control-over-your-code-with-amazon-q-developers-new-context-features/

In this blog post, I explore Amazon Q Developer’s latest enhancements to the IDE chat experience including increased context control, chat history and other conversation management features. On March 11th, 2025, my colleague published Take control of your code with Amazon Q Developer’s new context features detailing several improvements to the chat experience within VS Code. These included increased context transparency, the ability to select specific files or folders as context, prompt libraries for reusing prompts across conversations and projects, and project rules to help enforce coding standards and best practices across your teams.

Since then, Amazon Q Developer released additional features in VS Code to help provide users with more control over their conversations and enhance their ability to maintain development context across longer periods. These new capabilities make your interactions with Amazon Q Developer not just more efficient, but also more contextual and persistent—helping you maintain your development flow, even when work spans hours or days. Now, let’s jump in and explore some of the new features available today.

Conversation persistence

We’ve all been there—you’re deep in conversation with Amazon Q Developer, maybe you’re debugging an authentication problem, optimizing a complex database query, or designing a new API structure. You and Amazon Q Developer have been going back and forth, uncovering insights and piecing together solutions.

Then reality intervenes. You close your IDE to focus on another task, step away for a meeting, or maybe update your computer. When you finally return to your IDE, ready to dive back in, you’re met with a blank chat window. All that context, all those valuable exchanges—gone. You find yourself trying to reconstruct your train of thought, wasting precious time and momentum.

Amazon Q Developer now preserves your conversations across your IDE sessions. Instead of starting from scratch each time you open the IDE, you can now come back to your conversation and pick up right where you left off.

Conversation History Search

It isn’t just after a closed IDE session or coming back to your computer after a long-weekend that you want Amazon Q Developer to remember what you have been working on. Sometimes you need to reference a previous solution — maybe Amazon Q Developer gave you some good advice on optimizing your database queries that you want to use elsewhere, or maybe you decided to work on some front-end components so you could have fresh eyes for the API performance issue you’ve been working at.

Now, you can access your previous conversations with Amazon Q Developer by clicking on the search icon in the top right corner of your chat window. You can quickly locate specific discussions by typing keywords into the search bar, then either review the previous exchange or continue the conversation where you left off.

Screenshot of an Amazon Q interface showing a chat window. The user has requested to add Javadocs style comments to a Java file. The AI assistant is responding with an offer to help add Javadoc comments, mentioning a TODO for adding these comments and offering to provide a template.

Fig 1 – View chat history feature in the Amazon Q Developer VS Code chat interface.

Conversation Export

But what if you need to share these insights with a teammate or want to keep a local record for future reference? You can now easily export your chat sessions as markdown files, preserving all the valuable information for offline use or collaboration. To do this, click the export button located directly to the right of the chat history button. Alternatively, when browsing your chat history, you can export individual sessions by clicking the three dots on the right side of each conversation entry.

Screenshot of an Amazon Q chat interface showing a bulleted list of test requirements or specifications. The list includes items about using temporary files, testing success/failure scenarios, verifying edge cases and invalid inputs, testing public methods of a WordList class, and including cleanup annotation.

Fig 2 – Export chat feature in the Amazon Q Developer VS Code chat interface.

Increasing your control over context

Last July, we announced the ability to use @workspace in your chat session to provide comprehensive context across your entire application within the IDE. To provide more control over what Amazon Q Developer uses as context, earlier this year we released the ability to use the @ symbol in the chat to include specific folders or files as context for your conversation.

We are now taking your level of control one step further to allow you to use @ in your conversation to find and include classes, functions, and global variables into the input context. Rather than leaving it up to Amazon Q to determine the relevant files, folders, or functions for your request, you can continue to be more explicit with your request to receive the most relevant and accurate responses.

Screenshot of an Amazon Q interface showing a file search/navigation panel with "ja:" search query displaying Java-related files. The list includes various Java source files and configuration files from a Q-Words project, including controllers, models, and utility classes. At the bottom is a search input box with "@ja" and a note about Amazon Q Developer using generative AI.

Fig 3 – Context selection in Amazon Q Developer chat, using “@” to show relevant folders, files, functions.

Conclusion

Amazon Q Developer is continuing to evolve its features that help put developers in control of their coding experience. By offering conversation persistence, history search, and export capabilities, Amazon Q Developer works to create continuity that allows developers to maintain their momentum across sessions and easily revisit past solutions. The expanded context control features empower developers to fine-tune their interactions with Amazon Q Developer, and receive more precise and relevant responses.

To get started with these features in VS Code, visit the Amazon Q Developer Getting Started guide and explore the full range of capabilities that can help you create impressive software more efficiently.

Eva Knight

Eva Knight is a Worldwide Go-To-Market specialist at Amazon Web Services (AWS) focusing on generative AI across the software development lifecycle. Her journey at AWS began in 2022 as a Business Development Intern, transitioning to a full-time role after completing her Bachelor’s degree in Marketing and Information Systems from the University of Washington.

New Amazon EC2 P6-B200 instances powered by NVIDIA Blackwell GPUs to accelerate AI innovations

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6-b200-instances-powered-by-nvidia-blackwell-gpus-to-accelerate-ai-innovations/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6-B200 instances powered by NVIDIA B200 to address customer needs for high performance and scalability in artificial intelligence (AI), machine learning (ML), and high performance computing (HPC) applications.

Amazon EC2 P6-B200 instances accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing for foundation models (FMs) with reinforcement learning (RL) and distillation, multimodal training and inference, and HPC applications such as climate modeling, drug discovery, seismic analysis, and insurance risk modeling.

When combined with Elastic Fabric Adapter (EFAv4) networking, hyperscale clustering by EC2 UltraClusters, and advanced virtualization and security capabilities by AWS Nitro System, you can train and serve FMs with increased speed, scale, and security. These instances also deliver up to two times the performance for AI training (time to train) and inference (tokens/sec) compared to EC2 P5en instances.

You can accelerate time-to-market for training FMs and deliver faster inference throughput, which lowers inference cost and helps increase adoption of generative AI applications as well as increased processing performance for HPC applications.

EC2 P6-B200 instances specifications
New EC2 P6-B200 instances provide eight NVIDIA B200 GPUs with 1440 GB of high bandwidth GPU memory, 5th Generation Intel Xeon Scalable processors (Emerald Rapids), 2 TiB of system memory, and 30 TB of local NVMe storage.

Here are the specs for EC2 P6-B200 instances:

Instance size GPUs (NVIDIA B200) GPU
memory (GB)
vCPUs GPU Peer to peer (GB/s) Instance storage (TB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
P6-b200.48xlarge 8 1440 HBM3e 192 1800 8 x 3.84 NVMe SSD 8 x 400 100

These instances feature up to 125 percent improvement in GPU TFLOPs, 27 percent increase in GPU memory size, and 60 percent increase in GPU memory bandwidth compared to P5en instances.

P6-B200 instances in action
You can use P6-B200 instances in the US West (Oregon) AWS Region through EC2 Capacity Blocks for ML. To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console.

Select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for p6-b200.48xlarge instances. The total number of days that you can reserve EC2 Capacity Blocks is 1-14 days, 21 days, 28 days, or multiples of 7 up to 182 days. You can choose your earliest start date for up to 8 weeks in advance.

Now, your EC2 Capacity Block will be scheduled successfully. The total price of an EC2 Capacity Block is charged up front, and the price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

When launching P6-B200 instances, you can use AWS Deep Learning AMIs (DLAMI) to support EC2 P6-B200 instances. DLAMI provides ML practitioners and researchers with the infrastructure and tools to quickly build scalable, secure, distributed ML applications in preconfigured environments.

To run instances, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs.

You can integrate EC2 P6-B200 instances seamlessly with various AWS managed services such as Amazon Elastic Kubernetes Services (Amazon EKS), Amazon Simple Storage Service (Amazon S3), and Amazon FSx for Lustre. Support for Amazon SageMaker HyperPod is also coming soon.

Now available
Amazon EC2 P6-B200 instances are available today in the US West (Oregon) Region and can be purchased as EC2 Capacity blocks for ML.

Give Amazon EC2 P6-B200 instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 P6 instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Powering hybrid workloads with Amazon API Gateway

Post Syndicated from Mankaran Singh original https://aws.amazon.com/blogs/compute/powering-hybrid-workloads-with-amazon-api-gateway/

Amazon API Gateway can provide a single-entry point for all incoming API requests for Hybrid Workloads. You can use API Gateway to expose your resources in Amazon Virtual Private Cloud (VPC) and on-premises as REST APIs to external consumers. It provides a layer of abstraction between the API consumers and the backend services, allowing for centralized control. Routing all traffic through the API Gateway lets builders centrally enforce authentication, authorization, rate limiting, and other security features. This blog post describes how to configure API Gateway as an entry point to your on-premises resources.

Hybrid workloads can take advantage of API Gateway acting as single-entry point and provide a consistent interface for cloud and on-premises private API’s. You can connect API Gateway to resources within your private network through VPC link.

Figure 1 – private connectivity through VPC link

When private resources are located in different VPCs or AWS accounts, you can use AWS Transit Gateway or VPC peering to connect them.

Figure 2 – private connectivity through AWS Transit Gateway

You can also connect API Gateway to private resources hosted in your on-premises network.

Prerequisite

This blog assumes that you have an on-premises server hosting an API. Private connectivity between your AWS VPC and on-premises is needed, follow implementation step 1 for establishing private connectivity.

Solution overview

Figure 3 illustrates how to connect API Gateway’s REST API to on-premises application. The following steps detail the setup process.

Figure 3 – REST API architecture diagram for On-Premise applications

Implementation

The proposed solution can be implemented in six major steps:

Step 1. Enable VPC communication with on-premises network
Step 2. Setup Network Load Balancer for private integration with API gateway
Step 3. Create the VPC link
Step 4. Configure the API Gateway
Step 5. Create integration with VPC link
Step 6. Deploy the API

Step 1. Enable VPC communication with on-premises network

In this step we setup connectivity between Amazon VPC and on-premises network

  1. Create a VPC if one isn’t already configured.
  2. If no private connection between the VPC and your on-premises network exists, use either Virtual Private Gateway or AWS Transit Gateway to setup AWS Site-to-Site VPN or AWS Direct Connect.

Step 2. Setup Network Load Balancer for private integration with API gateway

In this step we setup Network Load Balancer required for private integration with API Gateway

  1. Sign in to the AWS Management Console and open the Amazon EC2 console at Amazon EC2 console
  2. Configure target group for your Network Load Balancer.
    Target group is used for request routing to your application. You will register on-premises server IPs in the target group. The load balancer checks the health of targets in this target group using the health check settings defined for the target group.

    1. Open the Amazon EC2 console at Amazon EC2 console.
    2. In the navigation pane, under Load Balancing, choose Target Groups.
    3. Choose Create target group.
    4. Keep the target type as IP addresses
    5. For Target group name, enter a name for the new target group.
    6. For Protocol, choose TCP, and for Port, choose the port where your application is running.
    7. For VPC, select the VPC created in PART A.
    8. For Health checks, keep the default settings.
    9. Choose Next.
    10. On the Register targets page, complete the following steps:
      1. Select the network as Other private IP address and Availability Zone as All
      2. Enter the IP addresses and port of the on-premises application, and then choose Include as pending below.
    11. Choose Create target group.

      Figure 4 – Amazon EC2 console create target group

  3. Configure your load balancer and listener
    To create a Network Load Balancer, you must first provide basic configuration information for your load balancer, such as a name, scheme, and IP address type. Then provide information about your network, and one or more listeners. A listener is a process that checks for connection requests. It is configured with a protocol and a port for connections from clients to the load balancer.

    1. For Load balancer name, enter a name for your load balancer.
    2. For Scheme and IP address type, keep the default values.
    3. For Network mapping, select the VPC that was previously created. Select one subnet each in at least two availability zones for high availability. By default, AWS assigns an IPv4 address to each load balancer node from the subnet for its Availability Zone.
    4. For Security groups, you will have a default security group associated for your VPC. Remove the default security group as it is not required for this setup.Review your configuration, and choose Create load balancer.
    5. For Listeners and routing, select the protocol as TCP and port of your application, and select the target group from the list. This configures a listener that accepts TCP traffic on port that you specify and forwards traffic to the selected target group by default.
    6. Review your configuration, and choose Create load balancer.

      Figure 5 – Amazon EC2 console create load balancer

  4. Turn off security group evaluation for PrivateLink for your Network Load Balancer.
    1. Go to your Network Load Balancer.
    2. Select the Security tab.
    3. Choose Edit.
    4. Clear “Enforce inbound rules on PrivateLink traffic”.
    5. Save changes

      Figure 6 – Amazon EC2 console -> Load Balancers -> Security; turn off security group evaluation

Step 3. Create the VPC Link

In this step we create a VPC link to connect your API and your Network Load Balancer. After you create a VPC link, you create private integrations to route traffic from your API to resources in your VPC through your VPC link and Network Load Balancer. To create VPC link, you need to do the following:

  1. Open the API Gateway console at Amazon API Gateway console
  2. Click on VPC Links in the navigation pane.
  3. Click on Create VPC Link and provide a name for the VPC link.
  4. Select the VPC link for REST APIs and provide the VPC link details following:
    1. For Name, enter the name for your VPC link
    2. For Description(optional), provide a description for your VPC link.
    3. For Target NLB, select the NLB created in the previous step from the dropdown.
  5. Choose Create

    Figure 7 – Amazon API Gateway console create a VPC link

Step 4. Create the API Gateway

In this step we create API Gateway that will have private integration with the Network Load Balancer

  1. Go back to the API Gateway Console Amazon API Gateway console
  2. Choose Create API. Under REST API, choose Build.
  3. Create Regional REST API.
    1. For API details, select New API
    2. For API name, provide a name for your API
    3. For Description(optional), provide a description for your API.
    4. For API endpoint type, select regional from the drop-down option.
  4. Choose Create API.

    Figure 8 – Amazon API Gateway console create REST API

Step 5. Create integration with VPC link

In this step we integrate the VPC link with the API created in the previous step.

  1. Create Resource
    1. From API Gateway console select Create resource
    2. Under Resource details, specify the resource path and resource name
    3. Choose Create resource

      Figure 9 – Amazon API Gateway console create resource for VPC link integration

  2. Create Method
    1. From API Gateway console select Create method.
    2. For Method type, select the desired method.
    3. For Integration type, select VPC link.
    4. Turn on VPC proxy integration.
    5. For HTTP method, select desired method.
    6. For VPC link, select the VPC link from the dropdown menu that was created in the previous steps.
    7. For Endpoint URL, enter a URL for the NLB created in the previous steps along with the port number. For eg: http://nlb-api-integration-xxxxxxxxxxxxxxxx.elb.us-east-1.amazonaws.com:80/on-prem. Assuming the endpoint is going to retrieve /on-prem resource.
    8. Choose Create method.
With the proxy integration, the API is ready for deployment. Otherwise, you need to proceed to set up appropriate method responses and integration responses.

      Figure 10 – Amazon API Gateway console create method and provide method details

      Figure 11 – Amazon API Gateway console create method and provide method details

Step 6. Deploy the API

Final step is to deploy the API. You can do that by using the following steps:

  1. Choose Deploy API
  2. For Stage, select New stage.
  3. For Stage name, enter a stage name.
  4. For Description(optional), enter a description.
  5. Choose Deploy

    Figure 12 – Amazon API Gateway console deploy the created API

Security

Security is the top priority at AWS and operates on a shared responsibility model between AWS and its customers. When managing hybrid APIs, implementing robust security measures is essential since these APIs serve as critical gateways to sensitive data and services. For detailed guidance on securing your REST APIs using API Gateway, please consult our documentation

Cleanup

To prevent incurring additional charges, remove the resources that were created during this walkthrough

  1. Open the API Gateway console.
  2. Select the APIs you created and select delete.
  3. Go to the VPC links in the navigation pane and select the VPC link created. Delete the VPC link.
  4. Within the EC2 console, go to load balancers in the navigation pane and delete the target group and NLB.

Conclusion

This post demonstrates how to configure API Gateway as an entry point for your on-premises resources, providing a unified API interface for your clients.

You can read more about working with API Gateway in AWS documentation and use these capabilities to create architectures to suit your specific requirements. For more serverless learning resources, visit Serverless Land.

Accelerate CI/CD pipelines with the new AWS CodeBuild Docker Server capability

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/accelerate-ci-cd-pipelines-with-the-new-aws-codebuild-docker-server-capability/

Starting today, you can use AWS CodeBuild Docker Server capability to provision a dedicated and persistent Docker server directly within your CodeBuild project. With Docker Server capability, you can accelerate your Docker image builds by centralizing image building to a remote host, which reduces wait times and increases overall efficiency.

From my benchmark, with this Docker Server capability, I reduced the total building time by 98 percent, from 24 minutes and 54 seconds to 16 seconds. Here’s a quick look at this feature from my AWS CodeBuild projects.

AWS CodeBuild is a fully managed continuous integration service that compiles source code, runs tests, and produces software packages ready for deployment. Building Docker images is one of the most common use cases for CodeBuild customers, and the service has progressively improved this experience over time by releasing features such as Docker layer caching and reserved capacity features to improve Docker build performance.

With the new Docker Server capability, you can reduce build time for your applications by providing a persistent Docker server with consistent caching. When enabled in a CodeBuild project, a dedicated Docker server is provisioned with persistent storage that maintains your Docker layer cache. This server can handle multiple concurrent Docker build operations, with all builds benefiting from the same centralized cache.

Using AWS CodeBuild Docker Server
Let me walk you through a demonstration that showcases the benefits with the new Docker Server capability.

For this demonstration, I’m building a complex, multi-layered Docker image based on the official AWS CodeBuild curated Docker images repository, specifically the Dockerfile for building a standard Ubuntu image. This image contains numerous dependencies and tools required for modern continuous integration and continuous delivery (CI/CD) pipelines, making it a good example of the type of large Docker builds that development teams regularly perform.


# Copyright 2020-2024 Amazon.com, Inc. or its affiliates. All Rights Reserved.
#
# Licensed under the Amazon Software License (the "License"). You may not use this file except in compliance with the License.
# A copy of the License is located at
#
#    http://aws.amazon.com/asl/
#
# or in the "license" file accompanying this file.
# This file is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, express or implied.
# See the License for the specific language governing permissions and limitations under the License.
FROM public.ecr.aws/ubuntu/ubuntu:20.04 AS core

ARG DEBIAN_FRONTEND="noninteractive"

# Install git, SSH, Git, Firefox, GeckoDriver, Chrome, ChromeDriver,  stunnel, AWS Tools, configure SSM, AWS CLI v2, env tools for runtimes: Dotnet, NodeJS, Ruby, Python, PHP, Java, Go, .NET, Powershell Core,  Docker, Composer, and other utilities
COMMAND REDACTED FOR BREVITY
# Activate runtime versions specific to image version.
RUN n $NODE_14_VERSION
RUN pyenv  global $PYTHON_39_VERSION
RUN phpenv global $PHP_80_VERSION
RUN rbenv  global $RUBY_27_VERSION
RUN goenv global  $GOLANG_15_VERSION

# Configure SSH
COPY ssh_config /root/.ssh/config
COPY runtimes.yml /codebuild/image/config/runtimes.yml
COPY dockerd-entrypoint.sh /usr/local/bin/dockerd-entrypoint.sh
COPY legal/bill_of_material.txt /usr/share/doc/bill_of_material.txt
COPY amazon-ssm-agent.json /etc/amazon/ssm/amazon-ssm-agent.json

ENTRYPOINT ["/usr/local/bin/dockerd-entrypoint.sh"]

This Dockerfile creates a comprehensive build environment with multiple programming languages, build tools, and dependencies – exactly the type of image that would benefit from persistent caching.

In the build specification (buildspec), I use the docker buildx build . command:

version: 0.2
phases:
  build:
    commands:
      - cd ubuntu/standard/5.0
      - docker buildx build -t codebuild-ubuntu:latest .

To enable the Docker Server capability, I navigate to the AWS CodeBuild console and select Create project. I can also enable this capability when editing existing CodeBuild projects.

I fill in all details and configuration. In the Environment section, I select Additional configuration.

Then, I scroll down and find Docker server configuration and select Enable docker server for this project. When I select this option, I can choose a compute type configuration for the Docker server. When I’m finished with the configurations, I create this project.

Now, let’s see the Docker Server capability in action.

The initial build takes approximately 24 minutes and 54 seconds to complete because it needs to download and compile all dependencies from scratch. This is expected for the first build of such a complex image.

For subsequent builds with no code changes, the build takes only 16 seconds and that shows 98% reduction in build time.

Looking at the logs, I can see that with Docker Server, most layers are pulled from the persistent cache:

The persistent caching provided by the Docker Server maintains all layers between builds, which is particularly valuable for large, complex Docker images with many layers. This demonstrates how Docker Server can dramatically improve throughput for teams running numerous Docker builds in their CI/CD pipelines.

Additional things to know
Here are a couple of things to note:

  • Architecture support – The feature is available for both x86 (Linux) and ARM builds.
  • Pricing – To learn more about pricing for Docker Server capability, refer to the AWS CodeBuild pricing page.
  • Availability – This feature is available in all AWS Regions where AWS CodeBuild is offered. For more information about the AWS Regions where CodeBuild is available, see the AWS Regions page.

You can learn more about the Docker Server feature in the AWS CodeBuild documentation.

Happy building! —

Donnie Prakoso


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Протест срещу жителите на София

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/protest-sreshtu-sofia/

Случващото се в София в момента е наказание за софиянци, че посмяха да гласуват за някой различен от поставено лице на Борисов, който да продължи схемите.

Затова Вълкът сега се включва, че ще спира извозването на боклука. Впрочем данните от СПТО показват, че именно неговите фирми са били сред най-злоупотребяващите съдейки по намаляването на курсовете за извозване на боклук, за които му плащахме милиони при Фандъкова. Също ресторантите под командата на „ония“ ще роптаят – надявам се на тъмно и сами. Утре и метрото вече с новото подставено лице за шеф може да се включи (ПП: оказа се, че няма), а в последните два дни профсъюз под контрола на съветник от БСП извадиха шофьорите въпреки, че преди това, но с човек на ГЕРБ са затривали исканията за по-високо заплащане.

Пропуски в общината има. Постигнатото далеч не е това, което се надявахме, зададохме и имаше амбиции да стане. Има много междуособици, цупене и недоверие между партньори в това управление и е изведено на преден план докато в Столичния общински съвет старите мутри и пионки си развяват коня и трудно може да се прокара нещо смислено само с гласовете стоящи горе-долу зад кмета.

Обаче… трудно може да се илюстрира по-добре колко неудобно е новото ръководство на общината въпреки всичко изброено от събитията тази седмица и думите на Борисов, че е наказание – от него за нас жителите на града. Също трудно може да се покаже по-ясно колко нездраво влияние имат сенчести хора във всякакви институции засягащи пряко ежедневието ни и как се обръща по команда това влияние в оръжие срещу самите нас.

Та, ако както казва Борисов трябва да си го изстрадаме, аз викам да си го изстрадаме. Да видим кой е по-голям инат.

The post Протест срещу жителите на София first appeared on Блогът на Юруков.

Access Amazon Redshift Managed Storage tables through Apache Spark on AWS Glue and Amazon EMR using Amazon SageMaker Lakehouse

Post Syndicated from Noritaka Sekiyama original https://aws.amazon.com/blogs/big-data/access-amazon-redshift-managed-storage-tables-through-apache-spark-on-aws-glue-and-amazon-emr-using-amazon-sagemaker-lakehouse/

Data environments in data-driven organizations are changing to meet the growing demands for analytics, including business intelligence (BI) dashboarding, one-time querying, data science, machine learning (ML), and generative AI. These organizations have a huge demand for lakehouse solutions that combine the best of data warehouses and data lakes to simplify data management with easy access to all data from their preferred engines.

Amazon SageMaker Lakehouse unifies all your data across Amazon Simple Storage Service (Amazon S3) data lakes and Amazon Redshift data warehouses, helping you build powerful analytics and artificial intelligence and machine learning (AI/ML) applications on a single copy of data. SageMaker Lakehouse gives you the flexibility to access and query your data  in place with all Apache Iceberg compatible tools and engines. It secures your data in the lakehouse by defining fine-grained permissions, which are consistently applied across all analytics and ML tools and engines. You can bring data from operational databases and applications into your lakehouse in near real time through zero-ETL integrations. It accesses and queries data in-place with federated query capabilities across third-party data sources through Amazon Athena.

With SageMaker Lakehouse, you can access tables stored in Amazon Redshift managed storage (RMS) through Iceberg APIs, using the Iceberg REST catalog backed by AWS Glue Data Catalog. This expands your data integration workload across data lakes and data warehouses, enabling seamless access to diverse data sources.

Amazon SageMaker Unified Studio, Amazon EMR 7.5.0 and higher, and AWS Glue 5.0 natively support SageMaker Lakehouse. This post describes how to integrate data on RMS tables through Apache Spark using SageMaker Unified Studio, Amazon EMR 7.5.0 and higher, and AWS Glue 5.0.

How to access RMS tables through Apache Spark on AWS Glue and Amazon EMR

With SageMaker Lakehouse, RMS tables are accessible through the Apache Iceberg REST catalog. Open source engines such as Apache Spark are compatible with Apache Iceberg, and they can interact with RMS tables by configuring this Iceberg REST catalog. You can learn more in Connecting to the Data Catalog using AWS Glue Iceberg REST extension endpoint.

Note that the Iceberg REST extensions endpoint is used when you access RMS tables. This endpoint is accessible through the Apache Iceberg AWS Glue Data Catalog extensions, which comes preinstalled on AWS Glue 5.0 and Amazon EMR 7.5.0 or higher. The extension library enables access to RMS tables using the Amazon Redshift connector for Apache Spark.

To access RMS backed catalog databases from Spark, each RMS database requires its own Spark session catalog configuration. Here are the required Spark configurations:

Spark config key Value
spark.sql.catalog.{catalog_name} org.apache.iceberg.spark.SparkCatalog
spark.sql.catalog.{catalog_name}.type glue
spark.sql.catalog.{catalog_name}.glue.id {account_id}:{rms_catalog_name}/{database_name}
spark.sql.catalog.{catalog_name}.client.region {aws_region}
spark.sql.extensions org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions

Configuration parameters:

  • {catalog_name}: Your chosen name for referencing the RMS catalog database in your application code
  • {rms_catalog_name}: The RMS catalog name as shown in the AWS Lake Formation catalogs section
  • {database_name}: The RMS database name
  • {aws_region}: The AWS Region where the RMS catalog is located

For a deeper understanding of how the Amazon Redshift hierarchy (databases, schemas, and tables) is mapped to the AWS Glue multilevel catalogs, you can refer to the Bringing Amazon Redshift data into the AWS Glue Data Catalog documentation.

In the following section, we demonstrate how to access RMS tables through Apache Spark using SageMaker Unified Studio JupyterLab notebooks with the AWS Glue 5.0 runtime and Amazon EMR Serverless.

Although we can bring existing Amazon Redshift tables into the AWS Glue Data catalog by creating a Lakehouse Redshift catalog from an existing Redshift namespace and provide access to a SageMaker Unified Studio project, in the following example, you’ll create a managed Amazon Redshift Lakehouse catalog directly from SageMaker Unified Studio and work with that.

Prerequisites

To follow these instructions, you must have the following prerequisites:

Create a SageMaker Unified Studio project

Complete the following steps to create a SageMaker Unified Studio project:

  1. Sign in to SageMaker Unified Studio.
  2. Choose Select a project on the top menu and choose Create project.
  3. For Project name, enter demo.
  4. For Project profile, choose All capabilities.
  5. Choose Continue.

  1. Leave the default values and choose Continue.
  2. Review the configurations and choose Create project.

You need to wait for the project to be created. Project creation can take about 5 minutes. When the project status changes to Active, select the project name to access the project’s home page.

  1. Make note of the Project role ARN because you’ll need it for next steps.

You’ve successfully created the project and noted the project role ARN. The next step is to configure a Lakehouse catalog for your RMS.

Configure a Lakehouse catalog for your RMS

Complete the following steps to configure a Lakehouse catalog for your RMS:

  1. In the navigation pane, choose Data.
  2. Choose the + (plus) sign.
  3. Select Create Lakehouse catalog to create a new catalog and choose Next.

  1. For Lakehouse catalog name, enter rms-catalog-demo.
  2. Choose Add catalog.

  1. Wait for the catalog to be created.

  1. In SageMaker Unified Studio, choose Data in the left navigation pane, then select the three vertical dots next to Redshift (Lakehouse) and choose Refresh to make sure the Amazon Redshift compute is active.

Create a new table in the RMS Lakehouse catalog:

  1. In SageMaker Unified Studio, on the top menu, under Build, choose Query Editor.
  2. On the top right, choose Select data source.
  3. For CONNECTIONS, choose Redshift (Lakehouse).
  4. For DATABASES, choose dev@rms-catalog-demo.
  5. For SCHEMAS, choose public.
  6. Choose Choose.

  1. In the query cell, enter and execute the following query to create a new schema:
create schema "dev@rms-catalog-demo".salesdb

  1. In a new cell, enter and execute the following query to create a new table:
create table salesdb.store_sales (ss_sold_timestamp timestamp, ss_item text, ss_sales_price float);

  1. In a new cell, enter and execute the following query to populate the table with sample data:
insert into salesdb.store_sales values ('2024-12-01T09:00:00Z', 'Product 1', 100.0),
('2024-12-01T11:00:00Z', 'Product 2', 500.0),
('2024-12-01T15:00:00Z', 'Product 3', 20.0),
('2024-12-01T17:00:00Z', 'Product 4', 1000.0),
('2024-12-01T18:00:00Z', 'Product 5', 30.0),
('2024-12-02T10:00:00Z', 'Product 6', 5000.0),
('2024-12-02T16:00:00Z', 'Product 7', 5.0);

  1. In a new cell, enter and run the following query to verify the table contents:
select * from salesdb.store_sales;

(Optional) Create an Amazon EMR Serverless application

IMPORTANT: This section is only required if you plan to test also using Amazon EMR Serverless. If you intend to use AWS Glue exclusively, you can skip this section entirely.

  1. Navigate to the project page. In the left navigation pane, select Compute, then select the Data processing Choose Add compute.

  1. Choose Create new compute resources, then choose Next.

  1. Select EMR Serverless.

  1. Specify emr_serverless_application as Compute name, select Compatibility as Permission mode, and choose Add compute.

  1. Monitor the deployment progress. Wait for the Amazon EMR Serverless application to complete its deployment. This process can take a minute.

Access Amazon Redshift Managed Storage tables through Apache Spark

In this section, we demonstrate how to query tables stored in RMS using a SageMaker Unified Studio notebook.

  1. In the navigation pane, choose Data
  2. Under Lakehouse, select the down arrow next to rms-catalog-demo
  3. Under dev, select the down arrow next salesdb, choose store_sales, and choose the three dots

SageMaker Lakehouse offers multiple analysis options: Query with Athena, Query with Redshift, and Open in Jupyter Lab notebook.

  1. Choose Open in Jupyter Lab notebook
  2. On the Launcher tab, choose Python 3 (ipykernel)

In SageMaker Unified Studio JupyterLab, you can specify different compute types for each notebook cell. Although this example demonstrates using AWS Glue compute (project.spark.compatibility), the same code can be executed using Amazon EMR Serverless by selecting the appropriate compute in the cell settings. The following table shows the connection type and compute values to specify when running PySpark code or Spark SQL code with different engines:

Compute option Pyspark code Spark SQL
Connection type Compute Connection type Compute
AWS Glue Pyspark project.spark.compatibility SQL project.spark.compatibility
Amazon EMR Serverless Pyspark emr-s.emr_serverless_application SQL emr-s.emr_serverless_application
  1. In the notebook cell’s top left corner, set Connection Type to PySpark and select spark.compatibility (AWS Glue 5.0) as Compute
  2. Execute the following code to initialize the SparkSession and configure rmscatalog as the session catalog for accessing the dev database under the rms-catalog-demo RMS catalog:
from pyspark.sql import SparkSession

catalog_name = "rmscatalog"
#Change <your_account_id> with your AWS account ID
rms_catalog_id = "<your_account_id>:rms-catalog-demo/dev"

#Change with your AWS region
aws_region="us-east-2"

spark = SparkSession.builder.appName('rms_demo') \
    .config(f'spark.sql.catalog.{catalog_name}', 'org.apache.iceberg.spark.SparkCatalog') \
    .config(f'spark.sql.catalog.{catalog_name}.type', 'glue') \
    .config(f'spark.sql.catalog.{catalog_name}.glue.id', rms_catalog_id) \
    .config(f'spark.sql.catalog.{catalog_name}.client.region', aws_region) \
    .config('spark.sql.extensions','org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions') \
    .getOrCreate()

  1. Create a new cell and switch the connection type from PySpark to SQL to execute Spark SQL commands directly
  2. Enter the following SQL statement to view all tables under salesdb (RMS schema) within rmscatalog:
SHOW TABLES IN rmscatalog.salesdb

  1. In a new SQL cell, enter the following DESCRIBE EXTENDED statement to view detailed information about the store_sales table in the salesdb schema:
DESCRIBE EXTENDED rmscatalog.salesdb.store_sales

In the output, you’ll observe that the Provider is set to iceberg. This indicates that the table is recognized as an Iceberg table, despite being stored in Amazon Redshift managed storage.

  1. In a new SQL cell, enter the following SELECT statement to view the content of the table
SELECT * FROM rmscatalog.salesdb.store_sales

Throughout this example, we demonstrated how to create a table in Amazon Redshift Serverless and seamlessly query it as an Iceberg table using Apache Spark within a SageMaker Unified Studio notebook.

Clean up

To avoid incurring future charges, clean up all created resources:

  1. Delete the created SageMaker Unified Studio project. This step will automatically delete Amazon EMR compute (for example, the Amazon EMR Serverless application) that was provisioned from the project:
    1. Inside SageMaker Studio, navigate to the demo project’s Project overview section.
    2. Choose Actions, then select Delete project.
    3. Type confirm and choose Delete project.
  1. Delete the created Lakehouse catalog:
    1. Navigate to the AWS Lake Formation page in the Catalogs section.
    2. Select the rms-catalog-demo catalog, choose Actions, then select Delete.
    3. In the confirmation window type rms-catalog-demo and then choose Drop.

Conclusion

In this post, we demonstrated how to use Apache Spark to interact with Amazon Redshift Managed Storage tables through Amazon SageMaker Lakehouse using the Iceberg REST catalog. This integration provides a unified view of your data across Amazon S3 data lakes and Amazon Redshift data warehouses, so you can build powerful analytics and AI/ML applications while maintaining a single copy of your data.

For additional workloads and implementations, visit Simplify data access for your enterprise using Amazon SageMaker Lakehouse.


About the Authors

Noritaka Sekiyama is a Principal Big Data Architect with Amazon Web Services (AWS) Analytics services. He’s responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.
Stefano Sandonà is a Senior Big Data Specialist Solution Architect at Amazon Web Services (AWS). Passionate about data, distributed systems, and security, he helps customers worldwide architect high-performance, efficient, and secure data solutions.
Derek Liu is a Senior Solutions Architect based out of Vancouver, BC. He enjoys helping customers solve big data challenges through Amazon Web Services (AWS) analytic services.

Raj Ramasubbu is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services (AWS). He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 18 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.

Angel Conde Manjon is a Sr. EMEA Data & AI PSA, based in Madrid. He has previously worked on research related to data analytics and AI in diverse European research projects. In his current role, Angel helps partners develop businesses centered on data and AI.


Appendix: Sample script for Lake Formation FGAC enabled Spark cluster

If you want to access RMS tables from Lake Formation FGAC enabled Spark cluster on AWS Glue or Amazon EMR, refer to the following code example:

from pyspark.sql import SparkSession

catalog_name = "rmscatalog"
rms_catalog_name = "123456789012:rms-catalog-demo/dev"
account_id = "123456789012"
region = "us-east-2"

spark = SparkSession.builder.appName('rms_demo') \
.config('spark.sql.defaultCatalog', catalog_name) \
.config(f'spark.sql.catalog.{catalog_name}', 'org.apache.iceberg.spark.SparkCatalog') \
.config(f'spark.sql.catalog.{catalog_name}.type', 'glue') \
.config(f'spark.sql.catalog.{catalog_name}.glue.id', rms_catalog_name) \
.config(f'spark.sql.catalog.{catalog_name}.client.region', region) \
.config(f'spark.sql.catalog.{catalog_name}.glue.account-id', account_id) \
.config(f'spark.sql.catalog.{catalog_name}.glue.catalog-arn',f'arn:aws:glue:{region}:{rms_catalog_name}') \
.config('spark.sql.extensions','org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions') \
.getOrCreate()

Revolutionizing agricultural knowledge management using a multi-modal LLM: A reference architecture

Post Syndicated from Nitin Eusebius original https://aws.amazon.com/blogs/architecture/revolutionizing-agricultural-knowledge-management-using-a-multi-modal-llm-a-reference-architecture/

Handwritten documents are still an important form of data capture in agribusiness. Paper-based handwritten documents can be the result of business culture, lack of internet connectivity, lack of mobile devices or computers, or environmental conditions in the field or in an industrial setting. Because of the physical nature of the document, there might be a delay in transcription or even no transcription into a digital system for enterprise reporting, causing critical information to be unavailable. Using generative AI, handwritten notes can be scanned to record and analyze the document and establish automated workflows for product procurement, the supply chain, and entry into customer relationship management (CRM), enterprise resource planning (ERP), and farm management information systems (FMIS).

Multi-modal large language models (LLMs) are transforming the agriculture industry by integrating diverse data types such as text, images, video, and audio. This approach enhances AI’s understanding and decision-making in farming contexts. For example, a multi-modal LLM can analyze images to identify crop issues, then generate targeted recommendations for irrigation or pest control. Combining handwritten documents and satellite imagery with the power of LLMs can lead to better crop analytics and better yields.

In this blog post, we introduce a reference architecture that offers an intelligent document digitization solution that converts handwritten notes, scanned documents, and images into editable, searchable, and accessible formats. Powered by Anthropic’s Claude 3 on Amazon Bedrock, the solution uses the sophisticated vision capabilities of LLMs to process a wide range of visual formats, preserving the original formatting while extracting text, tables, and images. This enables businesses to digitize their knowledge bases, facilitate seamless collaboration, and integrate the digitized content into their existing digital workflows, enhancing productivity and unlocking the full potential of their information assets.

A comprehensive solution and reference architecture

This reference architecture helps agricultural companies to automatically capture, analyze, and process handwritten notes and images with data and reports that are generated by individuals working in farm fields. This is an example of how to create an end-to-end solution to ingest these documents in image format with Amazon Bedrock. The processed information can be consumed by downstream systems such as CRM, ERP, and FMIS to make better data driven decisions.

The solution uses Anthropic’s Claude 3 multi modal model hosted in Amazon Bedrock. Amazon Bedrock is a fully managed service that offers a choice of high-performing foundation models (FMs) from leading AI companies through a single API, along with a broad set of capabilities to build generative AI applications with security, privacy, and responsible AI. Claude is Anthropic’s state-of-the-art LLM that offers important features for enterprises such as advanced reasoning, generating text from images, code generation, and multilingual processing. Claude 3 models have sophisticated vision capabilities and can process a wide range of visual formats, including photos, charts, graphs and technical diagrams. You can also use other models such as Llama 3.2 11B and 90B, which also support vision tasks.

The following diagram illustrates the reference solution.

Revolutionizing agricultural knowledge management using a multi-modal LLM: A reference architecture

The process includes the following steps:

  1. A field worker uploads handwritten notes in an image format using a static website on their mobile device. The static website is accessed through Amazon CloudFront and hosted in Amazon Simple Storage Service (Amazon S3).
  2. The worker is securely authenticated using Amazon Cognito.
  3. After the worker is authenticated, the uploaded handwritten notes are sent to Amazon Bedrock for processing using Amazon API Gateway.
  4. An AWS Lambda function stores and reads the image from Amazon S3. It sends the uploaded image and associated prompt information to Anthropic’s Claude 3 hosted in Amazon Bedrock.
  5. Anthropic’s Claude 3 processes the image. It recognizes the handwritten text and analyzes the converted text based on the given prompt.
  6. The converted digital text and analyzed information provided by Anthropic’s Claude 3 are stored in Amazon DynamoDB for further downstream processing.
  7. The field worker uses an app to access the converted digital text and newly processed information stored in Amazon DynamoDB through API Gateway.
  8. The processed information is published to Amazon Simple Notification Service (Amazon SNS) and is consumed by downstream systems.
  9. The field worker’s location details and processed image information are consumed by two different Amazon Simple Queue Service (Amazon SQS) queues to be stored in downstream systems.
  10. The downstream systems can include CRM, FMS, and FMIS.

Additionally, using this solution, geospatial information such as GPS and GIS information can be sent to the FMIS. This can help farmers in many ways including crop monitoring, soil health and nutrient management, pest control, water management, farm mapping, and much more.

Best practices and implementation guidelines

To implement a production-ready system, it’s important to consider the following best practices.

Responsible AI: Deployment of customer facing generative AI solutions raises concerns about responsible AI practices. To mitigate risks such as biased outputs, exposure of sensitive information, or misuse for malicious purposes, it’s crucial to implement robust safeguards and validation mechanisms. Amazon Bedrock Guardrails is a set of tools and services provided by AWS that you can use to implement safeguards and responsible AI practices when building applications with generative AI models.

Security: Follow secure coding practices throughout the development lifecycle to minimize vulnerabilities. Protect your web applications from common exploits by integrating with AWS WAF. The OWASP Top 10 for Large Language Model Applications is a set of guidelines that address the unique security risks associated with generative AI solutions. It covers vulnerabilities such as model inversion, membership inference, and adversarial attacks—all of which can compromise the confidentiality, integrity, and availability of LLMs.

Observability: Monitor all layers of a generative AI solution, including the application, prompt, LLM, knowledgebase, and response provided by the LLM. You can monitor health and performance using Amazon CloudWatch.

LLMOps: Implementing LLM operations (LLMOps) will help to scale your GenAI solutions. See FMOps/LLMOps: Operationalize generative AI and differences with MLOps for additional information.

Conclusion

In this post, we introduced a reference architecture for an intelligent document digitization solution in agriculture. This system uses Amazon Bedrock and the multi-modal capabilities of LLMs such as Anthropic’s Claude 3 to transform handwritten notes and multi-modal data into searchable, digital formats. We explored how this architecture bridges the gap between traditional field documentation and modern digital systems, enhancing data accessibility and decision-making in agribusiness.

The possibilities for customization and expansion are vast. For specific use cases, you can fine-tune the multi-modal model on your unique agricultural business data. You can also implement a combination of multi-modal processing and a specialized knowledge base using Amazon Bedrock Knowledge Bases, further enhancing the system’s accuracy and relevance.


About the Authors

The collective thoughts of the interwebz