Post Syndicated from Explosm.net original https://explosm.net/comics/american-gothic
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/american-gothic
New Cyanide and Happiness Comic
Post Syndicated from corbet original https://lwn.net/Articles/998221/
The kernel’s loadable-module facility allows code to be loaded into (and
sometimes removed from) a running kernel. Among other things, loadable
modules make it possible to run a kernel with only the subsystems needed
for the system’s hardware and workload. Loadable modules can also make it
easy for out-of-tree code to access parts of the kernel that developers
would prefer to keep private; this has led to many discussions in the
past. The topic has returned to the kernel’s mailing lists with two
different patch sets aimed at further tightening the restrictions applied
to loadable modules.
Post Syndicated from Arynn Crow original https://aws.amazon.com/blogs/security/secure-by-design-aws-enhances-centralized-security-controls-as-mfa-requirements-expand/
At Amazon Web Services (AWS), we’ve built our services with secure by design principles from day one, including features that set a high bar for our customers’ default security posture. Strong authentication is a foundational component in overall account security, and the use of multi-factor authentication (MFA) is one of the simplest and most effective ways to help prevent unauthorized individuals from gaining access to systems or data. We have found that enabling MFA prevents greater than 99% of password-related attacks. Today, we’re sharing progress from the past year since we first announced that we would require customers to improve their default security posture by requiring the use of MFA for root users in the AWS Management Console.
In recent years, the typical workplace has evolved significantly. With an increase in practices like hybrid work and bring-your-own-device (BYOD) policies, defining security boundaries became much more complex. Most organizations have adjusted their security perimeters to emphasize identity-based controls, which often made user passwords the new weakest link in the perimeter. Users sometimes choose low-complexity passwords for ease of use, or reuse complex passwords across multiple websites, which substantially increases risk when a website experiences a data breach.
We take many steps to improve our customers’ resilience against these types of risks. For example, we monitor online sources for compromised credentials and block customers from using these in AWS. We also guard against setting weak passwords, never suggest default passwords for users to use, and when we detect unusual sign-in activity for customers who haven’t yet enabled MFA, we validate the sign-in with one-time PIN challenges to their primary email address. Despite these measures, passwords alone remain inherently risky.
We recognized two key opportunities to improve the situation. The first is to accelerate our customers’ MFA adoption, raising the bar for default security posture at AWS by requiring MFA for highly privileged users. In May 2024, we began requiring MFA for AWS Organizations management account root users, starting with users in larger environments. Then, in June, we launched support for FIDO2 passkeys as an MFA method, to offer customers an additional highly secure but also user-friendly way to align with their security requirements. At the same time, we announced that our MFA requirements expanded to include root users in standalone accounts. After AWS Identity and Access Management (IAM) launched FIDO2 passkey support in June 2024, customer registration rates for phishing-resistant MFA increased by over 100%. Between April and October 2024, more than 750,000 AWS root users enabled MFA.
The second opportunity we recognized is to eliminate unnecessary passwords altogether. On top of the security issues with passwords, attempting to secure password-based authentication introduces operational overhead for customers, especially those operating at scale and those with regulatory requirements to rotate passwords periodically. Today, we are launching a new capability to centrally manage root access for accounts managed in AWS Organizations. This capability enables customers to greatly reduce the number of passwords they have to manage while still maintaining strong controls over the use of root principals. Customers can now enable centralized root access with a simple configuration change through the IAM console or the AWS CLI, a process which is described further in this post. Then, customers can remove the long-term credentials (including passwords or long-term access keys) of member account root users in their organizations. This will improve the security posture of our customers while simultaneously reducing their operational effort.
We strongly recommend that Organizations customers get started enabling our centralized root access feature today to experience these benefits. However, in cases where customers continue to maintain root users, it’s essential to make sure that these highly privileged credentials are well-protected. With enhanced support for our customers operating at scale, as well as additional features like passkeys, we’re expanding our MFA requirements to member accounts in AWS Organizations. Beginning in the Spring of 2025, customers who have not enabled central management of root access will be required to register MFA for their AWS Organizations member account root users in order to access the AWS Management Console. As with our previous expansions to management and standalone accounts, we will roll this change out gradually and notify individual customers who are required to take action in advance, to help customers adhere to the new requirements while minimizing impact to their day-to-day operations.
You can learn more about our new feature to centrally manage root access in the IAM User Guide, and more about using MFA at AWS in the AWS MFA in IAM User Guide.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/centrally-managing-root-access-for-customers-using-aws-organizations/
AWS Identity and Access Management (IAM) is launching a new capability allowing security teams to centrally manage root access for member accounts in AWS Organizations. You can now easily manage root credentials and perform highly privileged actions.
Managing root user credentials at scale
For a long time, Amazon Web Services (AWS) accounts were provisioned with highly privileged root user credentials, which had unrestricted access to the account. This root access, while powerful, also posed significant security risks. Each AWS account’s root user had to be secured by adding layers of protection like multi-factor authentication (MFA). Security teams were required to manage and secure these root credentials manually. The process involved rotating credentials periodically, storing them securely, and making sure that the credentials complied with security policies.
As our customers expanded their AWS environments, this manual approach became cumbersome and prone to error. For example, large enterprises operating hundreds or thousands of member accounts struggled to secure root access consistently across all accounts. The manual intervention not only added operational overhead but also created a lag in account provisioning, preventing full automation and increasing security risks. Root access, if not properly secured, could lead to account takeovers and unauthorized access to sensitive resources.
Furthermore, whenever specific root actions such as unlocking an Amazon Simple Storage Service (Amazon S3) bucket policy or an Amazon Simple Queue Service (Amazon SQS) resource policy were required, security teams had to retrieve and use root credentials, which only increased the attack surface. Even with rigorous monitoring and strong security policies, maintaining long-term root credentials opened doors to potential mismanagement, compliance risks, and manual errors.
Security teams began seeking a more automated, scalable solution. They needed a way to not only centralize the management of root credentials but also programmatically manage root access without needing long-term credentials in the first place.
Centrally manage root access
With the new ability to centrally manage root access, we address the longstanding challenge of managing root credentials across multiple accounts. This new capability introduces two essential capabilities: the central management of root credentials and root sessions. Together, they offer security teams a secure, scalable, and compliant way to manage root access across AWS Organizations member accounts.
Let’s first discuss the central management of root credentials. With this capability, you can now centrally manage and secure privileged root credentials across all accounts in AWS Organizations. Root credentials management allows you to:
But how can we make sure it remains possible to perform selected root actions on the accounts? This is the second capability we launch today: root sessions. It offers a secure alternative to maintaining long-term root access. Instead of manually accessing root credentials whenever privileged actions are required, security teams can now gain short-term, task-scoped root access to member accounts. This capability makes sure that actions such as unlocking S3 bucket policies or SQS queue policies can be performed securely without the need for long-term root credentials.
Root sessions key benefits include:
This new capability does not grant full root access. It provides temporary credentials for performing one of these five specific actions. The first three actions are possible with central management of root accounts. The last two come when enabling root sessions.
How to obtain root credentials on a member account
In this demo, I show you how to prepare your management account, create a member account without root credentials, and obtain temporary root credentials to make one of the five authorized API call on the member account. I assume you have an organization already created.
First, I create a member account.
aws organizations create-account    \
     --email [email protected] \
     --account-name 'Root Accounts Demo account'
{
    "CreateAccountStatus": {
        "Id": "car-695abd4ee1ca4b85a34e5dcdcd1b944f",
        "AccountName": "Root Accounts Demo account",
        "State": "IN_PROGRESS",
        "RequestedTimestamp": "2024-09-04T20:04:09.960000+00:00"
    }
}
Then, I enable the two new capabilities on my management account. Don’t worry, these commands don’t alter the behavior of the accounts in any way other than enabling use of the new capability.
➜  aws organizations enable-aws-service-access \
        --service-principal iam.amazonaws.com

➜  aws iam enable-organizations-root-credentials-management
{
    "OrganizationId": "o-rlrup7z3ao",
    "EnabledFeatures": [
        "RootCredentialsManagement"
    ]
}

➜  aws iam enable-organizations-root-sessions
{
    "OrganizationId": "o-rlrup7z3ao",
    "EnabledFeatures": [
        "RootSessions",
        "RootCredentialsManagement"
    ]
}
Alternatively, I can also use the console on the management account. Under Access management, I select Account settings.

Now, I’m ready to make requests to obtain temporary root credentials. I have to pass one of the five managed IAM policies to scope down the credentials to a specific action.
➜  aws sts assume-root \
       --target-principal <my member account id> \
       --task-policy-arn arn=arn:aws:iam::aws:policy/root-task/S3UnlockBucketPolicy

{
    "Credentials": {
        "AccessKeyId": "AS....XIG",
        "SecretAccessKey": "ao...QxG",
        "SessionToken": "IQ...SS",
        "Expiration": "2024-09-23T17:44:50+00:00"
    }
}
Once I obtain the access key ID, the secret access key, and the session token, I use them as usual with the AWS Command Line Interface (AWS CLI) or an AWS SDKs.
For example, I can pass these three values as environment variables.
$ export AWS_ACCESS_KEY_ID=ASIA356SJWJITG32xxx
$ export AWS_SECRET_ACCESS_KEY=JFZzOAWWLocoq2of5Exxx
$ export AWS_SESSION_TOKEN=IQoJb3JpZ2luX2VjEMb//////////wEaCXVxxxx
Now that I received the temporary credentials, I can make a restricted API call as root on the member account. First, I verify I now have root credentials. The Arn field confirms I’m working with the root account.
# Call get Caller Identity and observe I'm root in the member account
$ aws sts get-caller-identity
{
   "UserId": "012345678901",
   "Account": "012345678901",
   "Arn": "arn:aws:iam::012345678901:root"
}
Then, I use the delete-bucket-policy from S3 to remove an incorrect policy that has been applied to a bucket. The invalid policy removed all bucket access for everybody. Removing such policy requires root credentials.
aws s3api delete-bucket-policy --bucket my_bucket_with_incorrect_policy
When there is no output, it means the operation is successful. I can now apply a correct access policy to this bucket.
Credentials are valid only for 15 minutes. I wrote a short shell script to automate the process of getting the credentials as JSON, exporting the correct environment variables, and issuing the command I want to run as root.
Availability
Central management of root access is available at no additional cost in all AWS Regions except AWS GovCloud (US) and AWS China Regions, where there is no root account. Root sessions are available everywhere.
You can start using it through the IAM console, AWS CLI or AWS SDK. For more information, visit AWS account root user in our documentation and follow best practices for securing your AWS accounts.
Post Syndicated from Manos Samatas original https://aws.amazon.com/blogs/big-data/enrich-your-aws-glue-data-catalog-with-generative-ai-metadata-using-amazon-bedrock/
Metadata can play a very important role in using data assets to make data driven decisions. Generating metadata for your data assets is often a time-consuming and manual task. By harnessing the capabilities of generative AI, you can automate the generation of comprehensive metadata descriptions for your data assets based on their documentation, enhancing discoverability, understanding, and the overall data governance within your AWS Cloud environment. This post shows you how to enrich your AWS Glue Data Catalog with dynamic metadata using foundation models (FMs) on Amazon Bedrock and your data documentation.
AWS Glue is a serverless data integration service that makes it straightforward for analytics users to discover, prepare, move, and integrate data from multiple sources. Amazon Bedrock is a fully managed service that offers a choice of high-performing FMs from leading AI companies like AI21 Labs, Anthropic, Cohere, Meta, Mistral AI, Stability AI, and Amazon through a single API.
In this solution, we automatically generate metadata for table definitions in the Data Catalog by using large language models (LLMs) through Amazon Bedrock. First, we explore the option of in-context learning, where the LLM generates the requested metadata without documentation. Then we improve the metadata generation by adding the data documentation to the LLM prompt using Retrieval Augmented Generation (RAG).
This post uses the Data Catalog, a centralized metadata repository for your data assets across various data sources. The Data Catalog provides a unified interface to store and query information about data formats, schemas, and sources. It acts as an index to the location, schema, and runtime metrics of your data sources.
The most common method to populate the Data Catalog is to use an AWS Glue crawler, which automatically discovers and catalogs data sources. When you run the crawler, it creates metadata tables that are added to a database you specify or the default database. Each table represents a single data store.
LLMs are trained on vast volumes of data and use billions of parameters to generate outputs for common tasks like answering questions, translating languages, and completing sentences. To use an LLM for a specific task like metadata generation, you need an approach to guide the model to produce the outputs you expect.
This post shows you how to generate descriptive metadata for your data with two different approaches:
The solutions uses two generative AI models available in Amazon Bedrock: for text generation and Amazon Titan Embeddings V2 for text retrieval tasks.
The following sections describe the implementation details of each approach using the Python programming language. You can find the accompanying code in the GitHub repository. You can implement it step by step in Amazon SageMaker Studio and JupyterLab or your own environment. If you’re new to SageMaker Studio, check out the Quick setup experience, which allows you to launch it with default settings in minutes. You can also use the code in an AWS Lambda function or your own application.
In this approach, you use an LLM to generate the metadata descriptions. You employ prompt engineering techniques to guide the LLM on the outputs you want it to generate. This approach is ideal for AWS Glue databases with a small number of tables. You can send the table information from the Data Catalog as context in your prompt without exceeding the context window (the number of input tokens that most Amazon Bedrock models accept). The following diagram illustrates this architecture.

If you have hundreds of tables, adding all of the Data Catalog information as context to the prompt may lead to a prompt that exceeds the LLM’s context window. In some cases, you may also have additional content such as business requirements documents or technical documentation you want the FM to reference before generating the output. Such documents can be several pages that typically exceed the maximum number of input tokens most LLMs will accept. As a result, they can’t be included in the prompt as they are.
The solution is to use a RAG approach. With RAG, you can optimize the output of an LLM so it references an authoritative knowledge base outside of its training data sources before generating a response. RAG extends the already powerful capabilities of LLMs to specific domains or an organization’s internal knowledge base, without the need to fine-tune the model. It is a cost-effective approach to improving LLM output, so it remains relevant, accurate, and useful in various contexts.
With RAG, the LLM can reference technical documents and other information about your data before generating the metadata. As a result, the generated descriptions are expected to be richer and more accurate.
The example in this post ingests data from a public Amazon Simple Storage Service (Amazon S3): s3://awsglue-datasets/examples/us-legislators/all. The dataset contains data in JSON format about US legislators and the seats that they have held in the U.S. House of Representatives and U.S. Senate. The data documentation was retrieved from and the Popolo specification http://www.popoloproject.com/.
The following architecture diagram illustrates the RAG approach.

The steps are as follows:
To follow the steps in this post and deploy the solution in your own AWS account, refer to the GitHub repository.
You need the following prerequisite resources:
aws-gen-ai-glue-metadata-<random_sequence>. The following is an example inline policy:glue-catalog-genai_claude.ipynb.Now that you have completed the prerequisites, you can switch to the notebook environment to run the next steps. First, the notebook will create the required resources:
After you finish the setup steps, you will have an AWS Glue database called legislators.
The crawler creates the following metadata tables:
personsmembershipsorganizationseventsareascountriesThis is a semi-normalized collection of tables containing legislators and their histories.
Follow the rest of the steps in the notebook to complete the environment setup. It should only take a few minutes.
Now that you have completed the setup, you can inspect the Data Catalog to familiarize yourself with it and the metadata it captured. On the AWS Glue console, choose Databases in the navigation pane, then open the newly created legislators database. It should contain six tables, as shown in the following screenshot:

You can open any table to inspect the details. The table description and comment for each column is empty because they aren’t completed automatically by the AWS Glue crawlers.

You can use the AWS Glue API to programmatically access the technical metadata for each table. The following code snippet uses the AWS Glue API through the AWS SDK for Python (Boto3) to retrieve tables for a chosen database and then prints them on the screen for validation. The following code, found in the notebook of this post, is used to get the data catalog information programmatically.
Now that you’re familiar with the AWS Glue database and tables, you can move to the next step to generate table metadata descriptions with generative AI.
In this step, we generate technical metadata for a selected table that belongs to an AWS Glue database. This post uses the persons table. First, we get all the tables from the Data Catalog and include it as part of the prompt. Even though our code aims to generate metadata for a single table, giving the LLM wider information is useful because you want the LLM to detect foreign keys. In our notebook environment we install LangChain v0.2.1. See the following code:
In the preceding code, you instructed the LLM to provide a JSON response that fits the TableInput object expected by the Data Catalog update API action. The following is an example response:
You can also validate the JSON generated to make sure it conforms to the format expected by the AWS Glue API:
Now that you have generated table and column descriptions, you can update the Data Catalog.
In this step, use the AWS Glue API to update the Data Catalog:
The following screenshot shows the persons table metadata with a description.

The following screenshot shows the table metadata with column descriptions.

Now that you have enriched the technical metadata stored in Data Catalog, you can improve the descriptions by adding external documentation.
In this step, we add external documentation to generate more accurate metadata. The documentation for our dataset can be found online as an HTML. We use the LangChain HTML community loader to load the HTML content:
After you download the documents, split the documents into chunks:
Next, vectorize and store the documents locally and perform a similarity search. For production workloads, you can use a managed service for your vector store such as Amazon OpenSearch Service or a fully managed solution for implementing the RAG architecture such as Amazon Bedrock Knowledge Bases.
Next, include the catalog information along with the documentation to generate more accurate metadata:
The following is the response from the LLM:
Similar to the first approach, you can validate the output to make sure it conforms to the AWS Glue API.
Now that you have generated the metadata, you can update the Data Catalog:
Let’s inspect the technical metadata generated. You should now see a newer version in the Data Catalog for the persons table. You can access schema versions on the AWS Glue console.

Note the persons table description this time. It should differ slightly from the descriptions provided earlier:
The LLM demonstrated knowledge around the Popolo specification, which was part of the documentation provided to the LLM.
Now that you have completed the steps described in the post, don’t forget to clean up the resources with the code provided in the notebook so you don’t incur unnecessary costs.
In this post, we explored how you can use generative AI, specifically Amazon Bedrock FMs, to enrich the Data Catalog with dynamic metadata to improve the discoverability and understanding of existing data assets. The two approaches we demonstrated, in-context learning and RAG, showcase the flexibility and versatility of this solution. In-context learning works well for AWS Glue databases with a small number of tables, whereas the RAG approach uses external documentation to generate more accurate and detailed metadata, making it suitable for larger and more complex data landscapes. By implementing this solution, you can unlock new levels of data intelligence, empowering your organization to make more informed decisions, drive data-driven innovation, and unlock the full value of your data. We encourage you to explore the resources and recommendations provided in this post to further enhance your data management practices.
 Manos Samatas is a Principal Solutions Architect in Data and AI with Amazon Web Services. He works with government, non-profit, education and healthcare customers in the UK on data and AI projects, helping build solutions using AWS. Manos lives and works in London. In his spare time, he enjoys reading, watching sports, playing video games and socialising with friends.
 Anastasia Tzeveleka is a Senior GenAI/ML Specialist Solutions Architect at AWS. As part of her work, she helps customers across EMEA build foundation models and create scalable generative AI and machine learning solutions using AWS services.
Post Syndicated from Sumalatha Bachu original https://aws.amazon.com/blogs/big-data/how-finra-established-real-time-operational-observability-for-amazon-emr-big-data-workloads-on-amazon-ec2-with-prometheus-and-grafana/
This is a guest post by FINRA (Financial Industry Regulatory Authority). FINRA is dedicated to protecting investors and safeguarding market integrity in a manner that facilitates vibrant capital markets.
FINRA performs big data processing with large volumes of data and workloads with varying instance sizes and types on Amazon EMR. Amazon EMR is a cloud-based big data environment designed to process large amounts of data using open source tools such as Hadoop, Spark, HBase, Flink, Hudi, and Presto.
Monitoring EMR clusters is essential for detecting critical issues with applications, infrastructure, or data in real time. A well-tuned monitoring system helps quickly identify root causes, automate bug fixes, minimize manual actions, and increase productivity. Additionally, observing cluster performance and usage over time helps operations and engineering teams find potential performance bottlenecks and optimization opportunities to scale their clusters, thereby reducing manual actions and improving compliance with service level agreements.
In this post, we talk about our challenges and show how we built an observability framework to provide operational metrics insights for big data processing workloads on Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2) clusters.
In today’s data-driven world, organizations strive to extract valuable insights from large amounts of data. The challenge we faced was finding an efficient way to monitor and observe big data workloads on Amazon EMR due to its complexity. Monitoring and observability for Amazon EMR solutions come with various challenges:
Effective observability for Amazon EMR requires a combination of the right tools, practices, and strategies to address these challenges and provide reliable, efficient, and cost-effective big data processing.
The Ganglia system on Amazon EMR is designed to monitor complete cluster and all nodes’ health, which shows several metrics like Hadoop, Spark, and JVM. When we view the Ganglia web UI in a browser, we see an overview of the EMR cluster’s performance, detailing the load, memory usage, CPU utilization, and network traffic of the cluster through different graphs. However, with Ganglia’s deprecation announced by AWS for higher versions of Amazon EMR, it became important for FINRA to build this solution.
Insights drawn from the post Monitor and Optimize Analytic Workloads on Amazon EMR with Prometheus and Grafana inspired our approach. The post demonstrated how to set up a monitoring system using Amazon Managed Service for Prometheus and Amazon Managed Grafana to effectively monitor an EMR cluster and use Grafana dashboards to view metrics to troubleshoot and optimize performance issues.
Based on these insights, we completed a successful proof of concept. Next, we built our enterprise central monitoring solution with Managed Prometheus and Managed Grafana to mimic Ganglia-like metrics at FINRA. Managed Prometheus allows for real-time high-volume data collection, which scales the ingestion, storage, and querying of operational metrics as workloads increase or decrease. These metrics are fed to the Managed Grafana workspace for visualizations.
Our solution includes a data ingestion layer for every cluster, with configuration for metrics collection through a custom-built script stored in Amazon Simple Storage Service (Amazon S3). We also installed Managed Prometheus at startup for EC2 instances on Amazon EMR through a bootstrap script. Additionally, application-specific tags are defined in the configuration file to optimize inclusion and collect the specific metrics.
After Managed Prometheus (installed on EMR clusters) collects the metrics, they are sent to a remote Managed Prometheus workspace. Managed Prometheus workspaces are logical and isolated environments dedicated to Managed Prometheus servers that manage specific metrics. They also provide access control for authorizing who or what sends and receives metrics from that workspace. You can create one more workspace by account or application depending on the need, which facilitates better management.
After metrics are collected, we built a mechanism to render them on Managed Grafana dashboards that are then used for consumption through an endpoint. We customized the dashboards for task-level, node-level, and cluster-level metrics so they can be promoted from lower environments to higher environments. We also built several templated dashboards that display node-level metrics like OS-level metrics (CPU, memory, network, disk I/O), HDFS metrics, YARN metrics, Spark metrics, and job-level metrics (Spark and JVM), maximizing the potential for each environment through automated metric aggregation in each account.
We chose a SAML-based authentication option, which allowed us to integrate with existing Active Directory (AD) groups, helping minimize the work needed to manage user access and grant user-based Grafana dashboard access. We arranged three main groups—admins, editors, and viewers—for Grafana user authentication based on user roles.
Through elaborate monitoring automation, these desired metrics are pushed to Amazon CloudWatch. We use CloudWatch for necessary alerting when it exceeds the desired thresholds for each metric.
The following diagram illustrates the solution architecture.

The following screenshots showcase example dashboards.


In this post, we shared how FINRA enhanced data-driven decision-making with comprehensive EMR workload observability to optimize performance, maintain reliability, and gain critical insights into big data operations, leading to operational excellence.
FINRA’s solution enabled the operations and engineering teams to use a single pane of glass for monitoring big data workloads and quickly detecting any operational issues. The scalable solution significantly reduced time to resolution and enhanced our overall operational stance. The solution empowered the operations and engineering teams with comprehensive insights into various Amazon EMR metrics like OS levels, Spark, JMX, HDFS, and Yarn, all consolidated in one place. We also extended the solution to use cases such as Amazon Elastic Kubernetes Service (Amazon EKS) clusters, including EMR on EKS clusters and other applications, establishing it as a one-stop system for monitoring metrics across our infrastructure and applications.
 Sumalatha Bachu is Senior Director, Technology at FINRA. She manages Big Data Operations which includes managing petabyte-scale data and complex workloads processing in cloud. Additionally, she is an expert in developing Enterprise Application Monitoring and Observability Solutions, Operational Data Analytics, & Machine Learning Model Governance work flows. Outside of work, she enjoys doing yoga, practicing singing, and teaching in her free time.
 PremKiran Bejjam is Lead Engineer Consultant at FINRA, specializing in developing resilient and scalable systems. With a keen focus on designing monitoring solutions to enhance infrastructure reliability, he is dedicated to optimizing system performance. Beyond work, he enjoys quality family time and continually seeks out new learning opportunities.
 Akhil Chalamalasetty is Director, Market Regulation Technology at FINRA. He is a Big Data subject matter expert specializing in building cutting edge solutions at scale along with optimizing workloads, data, and its processing capabilities. Akhil enjoys sim racing and Formula 1 in his free time.
Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/updated-whitepaper-architecting-for-pci-dss-segmentation-and-scoping-on-aws/
Our mission at AWS Security Assurance Services is to assist with Payment Card Industry Data Security Standard (PCI DSS) compliance for Amazon Web Services (AWS) customers. We work closely with AWS customers to answer their questions about compliance on the AWS Cloud, finding and implementing solutions, and optimizing their controls and assessments. We’ve compiled the most frequent and foundational questions in the updated Architecting for PCI DSS Scoping and Segmentation on AWS whitepaper, which aligns with the PCI Council’s Information Supplement: Guidance for PCI DSS Scoping and Network Segmentation.
This whitepaper provides guidance on how you can properly define the scope of your PCI DSS 4.0 workloads that are running in the AWS Cloud. The whitepaper describes how to define segmentation boundaries between your in-scope and out-of-scope resources by using AWS Cloud–based services, provides recommendations for segmentation best practices for various workloads, and offers insights into network traffic flows for segmentation at both east-west (internal) and north-south (external) network communication paths.
This update brings significant enhancements by offering practical and actionable design patterns at the network layer, tailored to support PCI DSS. For readers who have consulted the previous version of the whitepaper, this update brings the following important enhancements:
The whitepaper is not only intended for engineers and solution builders, but also serves as a guide for Qualified Security Assessors (QSAs) and internal security assessors (ISAs) to better understand the various segmentation controls that are available within AWS products and services, along with associated scoping considerations.
Compared to on-premises environments, software-defined networking on AWS transforms the scoping process for applications by providing additional segmentation controls beyond network segmentation. Thoughtful design of your applications and selection of security-impacting services for implementing your required controls can reduce the number of systems and services in your cardholder data environment (CDE).
New security and governance tools available from AWS and the AWS Partner Network (APN) enable you to build business-as-usual compliance and automated security tasks so you can shift your focus to scaling and innovating your business.
If you have questions or want to learn more, contact your account executive, or leave a comment below.
Post Syndicated from jzb original https://lwn.net/Articles/997559/
The Fedora Project is set to welcome a second desktop edition to its
lineup after months (or years, depending when one starts the clock)
of discussions. The project recently decided to allow a new working group to
move forward with a KDE Plasma Desktop edition that will sit
alongside the existing GNOME-based Fedora Workstation
edition. This puts KDE on a more equal footing within the project,
which, it is hoped, will bring more contributors and users interested
in KDE to adopt Fedora as their Linux distribution of choice.
Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/11/15/new-idr-log-search-enhancements-accelerate-streamline-and-simplify-investigations/
In today’s cybersecurity landscape, organizations need robust detection and response solutions to stay ahead of evolving threats. Rapid7’s InsightIDR, the foundation of our Managed Detection and Response (MDR) service, empowers security teams with advanced analytics, automation, and expert-led investigations. Whether used as a standalone SIEM and XDR platform or in combination with MDR, InsightIDR’s latest Log Search enhancements bring even more value across the board. These updates accelerate response times, simplify complex queries, and improve the investigation process for both our MDR clients and product-only customers.
These updates, including Simplified Query Building, Pre-Computed Queries, and Bloom Filters, enhance the speed, accuracy, and accessibility of log search for security teams, ensuring faster, more targeted threat investigations for organizations.
Let’s explore how these updates elevate the detection and response lifecycle.
A key element of any detection and response solution is the ability to quickly turn data into actionable insights. Simplified Query Building enables analysts to construct and refine log searches faster, without complex syntax or technical details. This user-friendly interface enables any InsightIDR user, regardless of technical expertise, to create advanced queries through point-and-click prompts, accessing critical data quickly to streamline investigations.
By lowering the barrier to creating queries, Simplified Query Building provides organizations with timely, data-backed insights into incidents, reducing investigation time for both Rapid7’s MDR team and InsightIDR customers. This update ensures that every security team member, regardless of tenure, can access and leverage the power of InsightIDR’s log data without becoming bogged down by technical complexities.
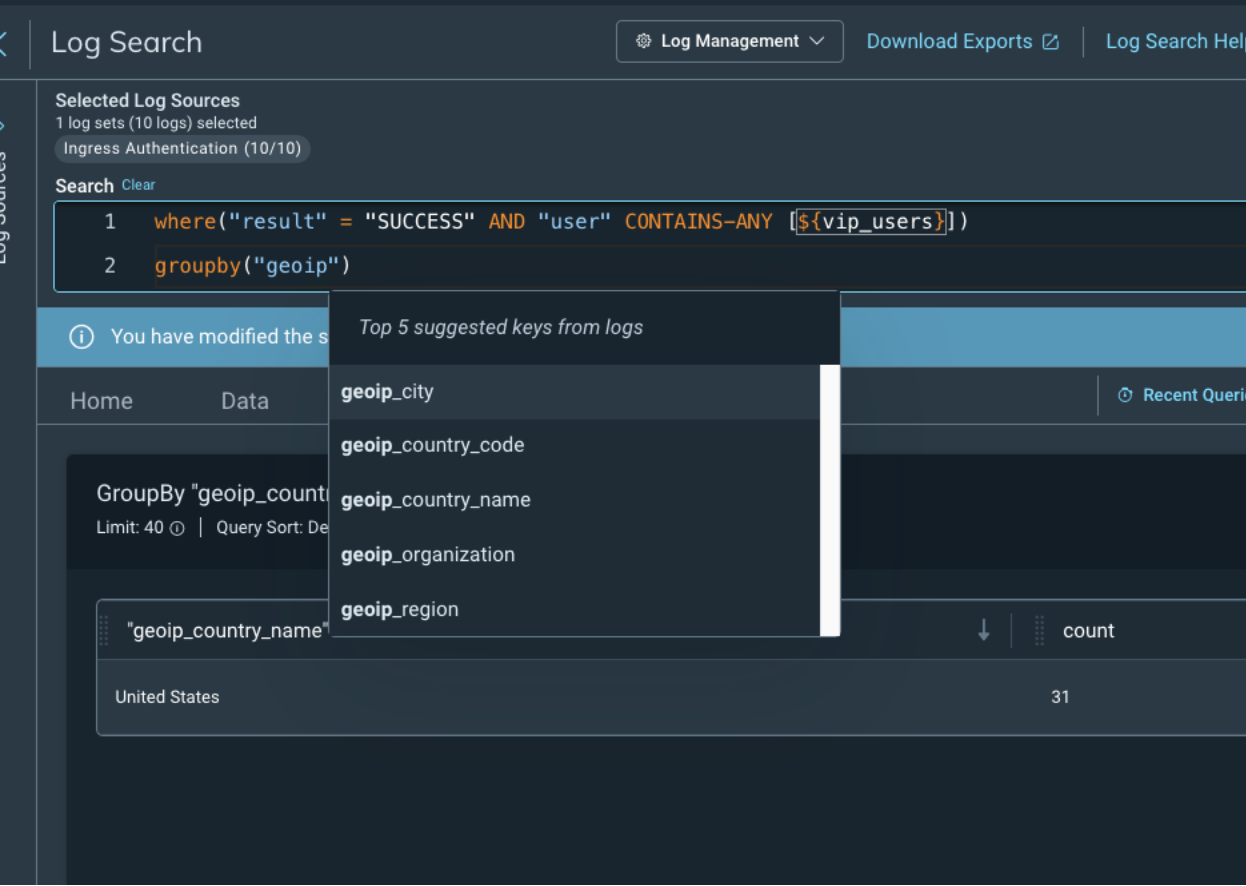
Time is critical when it comes to threat response.With Pre-Computed Queries (PCQs), both MDR and product-only customers benefit from reduced log search times. PCQs enable predictably fast, near-instant access to insights by pre-calculating query results in real-time as data arrives, enhancing responsiveness for all InsightIDR users.
Customer Feedback
“As an MSSP, InsightIDR’s ability to handle large amounts of data is key for identifying threats in our client environments. Pre-Computed Queries have reduced return times for complex searches by over 70%, allowing us to create more impactful insights for our clients.”
— Mat Cornish, Technical Director, Longwall Security
While InsightIDR already supports saving queries for reuse, PCQs take it further by pre-computing results, helping analysts to instantly identify patterns or gather evidence. Additionally, the Log Search home tab organizes queries by “Recent,” “Saved,” and “Pre-computed,” enabling users to quickly find what they need for streamlined incident handling. Whether you’re a customer conducting an in-house investigation or part of Rapid7’s MDR team, PCQs ensure faster insights and more efficient incident response.
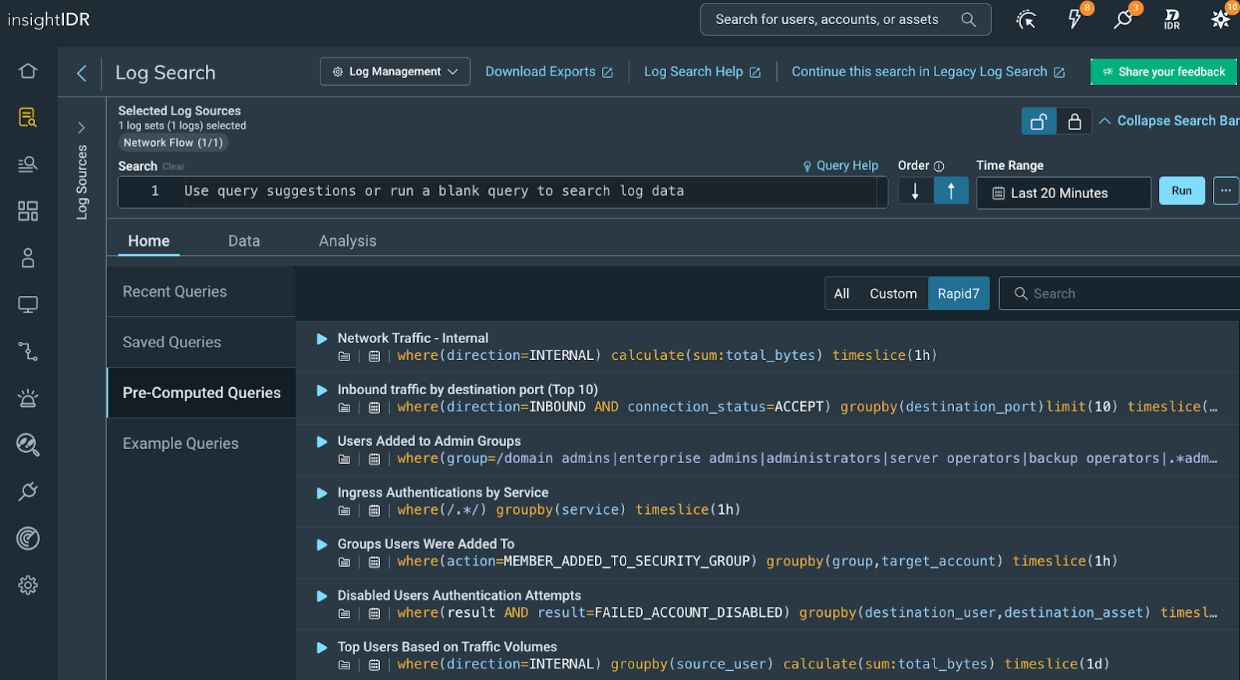
Not all queries can be pre-calculated in advance. Security teams are frequently asked questions about potential exposure to specific indicators of compromise (IoCs), such as flagged IP addresses or hash values. With Bloom Filters, both MDR and product-only customers gain a performance boost in search time for precise threat hunts by reducing unnecessary data processing.
For exact match searches, like identifying a compromised IP address or hunting for a suspicious hash value where(hash.sha=”…”), Bloom Filters optimize search time by ruling out irrelevant data – enabling the algorithm to skip logs that would not have matches. This enhancement is implemented on the backend and occurs automatically for any search that contains an exact match key-value pair. Reducing the search space means accelerating analysts’ ability to hone in on the exact information they need, cutting down investigation time dramatically.
A recent research effort into InsightIDR’s new indexing approach, which leverages Bloom Filters, showed impressive results with:
Whether you’re a Rapid7 MDR customer or an InsightIDR product-only user, these Log Search updates significantly enhance detection and response capabilities. By reducing search times, simplifying complex queries, and pinpointing threats with greater accuracy, we provide every InsightIDR user with faster, more effective security outcomes.
This means:
Want to see these improvements in action? Contact us today to learn how Rapid7’s MDR service can protect your organization. You can also try InsightIDR for free with a 30-day trial.
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/lenovo-has-a-cxl-memory-monster-astera-labs-intel-xeon/
We saw a Lenovo server supporting up to 128x 128GB DDR5 RDIMMs for massive memory capacity using Astera Labs Leo CXL memory controllers
The post Lenovo Has a CXL Memory Monster with 128x 128GB DDR5 DIMMs appeared first on ServeTheHome.
Post Syndicated from daroc original https://lwn.net/Articles/998291/
Security updates have been issued by Debian (curl and unbound), Fedora (krb5 and microcode_ctl), Red Hat (kernel and kernel-rt), SUSE (glib2, python3-wxPython, and ucode-intel), and Ubuntu (golang-1.17, golang-1.18, libgd2, linux, linux-aws, linux-kvm, linux-lts-xenial, linux-gke, linux-raspi, linux-raspi, linux-raspi-5.4, and php7.0, php7.2).
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=AbX7oOu7Ka0
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=NAolb2DYDo8
Post Syndicated from Caitlin Condon original https://blog.rapid7.com/2024/11/15/etr-zero-day-exploitation-targeting-palo-alto-networks-firewall-management-interfaces/
On Friday, November 8, 2024, cybersecurity firm Palo Alto Networks (PAN) published a bulletin (PAN-SA-2024-0015) advising firewall customers to take steps to secure their firewall management interfaces amid unverified rumors of a possible new vulnerability. Rapid7 threat intelligence teams have also been monitoring rumors of a possible zero-day vulnerability, but until now, those rumors have been unsubstantiated.
Late in the evening of Thursday, November 14, the Palo Alto Networks advisory was updated to note that PAN had “observed threat activity exploiting an unauthenticated remote command execution vulnerability against a limited number of firewall management interfaces which are exposed to the Internet.” The firm indicated they are actively investigating. As of the morning of Friday, November 15, there is no CVE or fix for the issue PAN has identified.
Per the vendor bulletin:
In lieu of a fix, Palo Alto Networks customers should ensure access to the firewall management interface is configured correctly in accordance with PAN’s recommended best practice deployment guidelines — namely, that access is restricted to trusted internal IPs only and the management interface is not exposed or accessible to the internet. More guidance is available here.
The Palo Alto Networks advisory also has directions on identifying internet-facing management interfaces and/or devices that may otherwise require remediation action. Rapid7 strongly recommends reviewing the advisory and configuration guidance. We will update this blog with further information as it becomes available, but as always, we encourage Palo Alto Networks customers to refer to the vendor advisory for the latest information.
Post Syndicated from Емилия Милчева original https://www.toest.bg/osmite-izbori-poveche-otrova-ili-poveche-demokratsiya/

Още преди да бъдат преброени бюлетините от седмите парламентарни избори за последните три години в България, политолози вече предсказваха осмите. Защо да се боим от избори – изборите лекуват демокрацията! Но каква демокрация? В държава, в която политическата нестабилност и сътресения станаха неотменни спътници в последните четири години, гласуването – това върховно право на всеки гражданин на демократично общество, бе сериозно опорочено, доверието в институциите, политическите лидери и партиите – силно снижено, а политическата апатия – качена в небесата. Изборите имат все по-слаба връзка с бъдещи политики, а партиите печелят избиратели благодарение на страстите, които разпалват, с битки и ненавист.
Как едни осми избори биха излекували поне една от тия болести на българската демокрация? За да успеят, ще трябва да възстановят истинския демократичен процес, в който гласуването е не само акт на участие, но и реален механизъм за избор на бъдещи политики. В момента изглежда, че българските политици преследват далеч по-прагматични цели, а политиката не само че се поляризира до крайност, но и полюсите си имат лица.
През последните години на политическа криза лидерската роля не просто на президента като институция, а на Румен Радев като личност укрепна. На „Дондуков“ 2 се е окопала една много силна фигура със симпатии към Кремъл, но и към унгарския лидер Орбан. От 2021 г. насам Радев влезе в сблъсъци с лидерите на най-големите политически сили. Започна от най-могъщия, какъвто безспорно е създателят и водач на ГЕРБ Бойко Борисов, трикратен премиер. След поредица от взаимни нападки и ескалация на напрежение с протестите през лятото на 2021 г., с вдигнатия юмрук и нахлуването в Президентството, двамата днес са в студен мир, а понякога влизат и в тактически съдружия.
Радев продължи с тези, на които осигури трамплин за политиката, като ги покани в служебното си правителство – създателите и съпредседатели на „Продължаваме промяната“ Кирил Петков и Асен Василев. Последваха сериозни схватки, а заради силата, която получи президентът с управлението на служебните си правителства, ПП и „Демократична България“ подеха инициативата за промяна на Конституцията, която да му отнеме тези правомощия. С новата конфигурация в Конституционния съд и внесената жалба срещу промените в Конституцията има шанс те да паднат, а Румен Радев – да си възвърне правомощията. Томахавките с ПП–ДБ сега са заровени, а заради общия враг – олигарха Делян Пеевски – Радев и коалицията са и (временно) в един лагер.
От началото на втория си мандат Радев влезе в конфликт с председателката на БСП Корнелия Нинова – един от хората, проправили му пътя в политиката. Но Нинова вече е изключена от БСП, а настоящото ръководство на социалистите се съобразява с Радев. В депутатските листи беше включена близката до него Наталия Киселова, която сега е предлагана и за председател на парламента от името на БСП – Обединена левица.
Пеевски се е позиционирал срещу Радев, когото нарича Мистър Кеш, подобно на противопоставянето с Борисов през 2021 г. заедно с тогавашния главен прокурор Иван Гешев. В действителност тази вражда легитимира и двамата като изтъкнати борци на сумо на политическия тепих.
Силата на Румен Радев не би била в политически проект – любима дъвка от поне две години, а във възстановяване на опцията за служебните кабинети. Дори инициаторите за конституционните промени ПП–ДБ вече са се отказали от публичната им защита и от аргумента, че не бива да се съсредоточава толкова власт в президентската институция. А с Румен Радев за президент всички евроскептични партии и формации с проруски и националпопулистки уклон, нароили се в последните години, утвърждават влиянието си сред обществото и формират един силен блок. Осмите избори ще са още един бонус за този тренд.
Изявлението на вицепрезидентката Илияна Йотова, обявила 51-вия парламент за нелегитимен, както и жалбите за частично/пълно касиране на изборите хвърлят сянка върху служебното правителство на Димитър Главчев (а значи и върху ГЕРБ), което ги организира. От президентската институция не пропускат да изтъкнат при всеки удобен случай, че при техните служебни кабинети подобни безобразия не са се случвали. (Затова пък има други – като например 13-годишния договор за природен газ с турската държавна компания „Боташ“, получила достъп до българската газопреносна мрежа, а съответно и до европейската, срещу ниска такса. А „Булгаргаз“ поема задължение да плаща дневно по 486 514 долара на „Боташ“ от 1 януари 2023 г.)
Но освен министъра на вътрешните работи Атанас Илков, към когото са насочени значителни критики, отговорност носи и излъченият от служебния кабинет координатор на изборите Росен Карадимов. Той беше началник на кабинета на премиера на тройната коалиция Сергей Станишев, а един от служебните кабинети на Гълъб Донев, т.е. на президента, го постави за председател на Надзорния съвет на държавната Българска банка за развитие.
Все още не е ясно дали решението за касиране на изборите от Конституционния съд няма да дойде, след като парламентът вече ще е в отпуск за поредната предизборна кампания. Но тежките съмнения за честността на вота от 27 октомври изиграха своята роля.
Едни бъдещи парламентарни избори през март 2025 г. обаче няма да повторят настоящото разпределение на силите в 51-вия парламент. МЕЧ може и да не постигнат същия резултат. ГЕРБ ще бъдат омаломощени, а раздалечаването в коалицията ПП–ДБ на двете ѝ съставни части ще продължи. БСП я очаква тежък конгрес в началото на 2025 г. ДПС никога вече няма да е каквото беше преди разцеплението, а вероятно и двете партии, появили се на мястото на единното Движение, ще имат по-слаби резултати. Въпреки плашилата, които размахва Пеевски.
Най-важното обаче е, че в хипотезата на осми избори те ще се проведат след избора на нов главен прокурор в началото на януари. А политическата задача за повечето парламентарно представени сили (не и за ГЕРБ–СДС, нито за ДПС – Ново начало) е да бъде спрян изборът на единствения кандидат – изпълняващия функциите главен прокурор Борислав Сарафов. Освен това политическите сили ще се опитат да изберат председател на парламента, който не е от партията, спечелила изборите – ГЕРБ. При поредни предсрочни избори той ще е бъдещият министър-председател и всички участвали в избора ще бъдат представени в евентуално служебно правителство.
Какво става със стратегическите задачи за България – еврозона, Шенген, обновяване на регулатори и политически представители в съдебната система, реформи и План за възстановяване и устойчивост? Сигналите, които идват от 51-вия парламент, са в регистъра на популизма, а гражданите трудно се ориентират в мъглявината от безплодна политическа реторика. Партиите не правят стратегии, само тактически ходове.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/good-essay-on-the-history-of-bad-password-policies.html
Stuart Schechter makes some good points on the history of bad password policies:
Morris and Thompson’s work brought much-needed data to highlight a problem that lots of people suspected was bad, but that had not been studied scientifically. Their work was a big step forward, if not for two mistakes that would impede future progress in improving passwords for decades.
First, was Morris and Thompson’s confidence that their solution, a password policy, would fix the underlying problem of weak passwords. They incorrectly assumed that if they prevented the specific categories of weakness that they had noted, that the result would be something strong. After implementing a requirement that password have multiple characters sets or more total characters, they wrote:
These improvements make it exceedingly difficult to find any individual password. The user is warned of the risks and if he cooperates, he is very safe indeed.
As should be obvious now, a user who chooses “p@ssword” to comply with policies such as those proposed by Morris and Thompson is not very safe indeed. Morris and Thompson assumed their intervention would be effective without testing its efficacy, considering its unintended consequences, or even defining a metric of success to test against. Not only did their hunch turn out to be wrong, but their second mistake prevented anyone from proving them wrong.
That second mistake was convincing sysadmins to hash passwords, so there was no way to evaluate how secure anyone’s password actually was. And it wasn’t until hackers started stealing and publishing large troves of actual passwords that we got the data: people are terrible at generating secure passwords, even with rules.
Post Syndicated from Надежда Цекулова original https://www.toest.bg/opitat-na-centar-anna-froyd-za-podkrepa-na-mladezhi/

Д-р Питър Фугъл е клиничен психолог. Близо четири десетилетия работи в услуги за деца с различни нужди, включително увреждания и детски психични заболявания. От 1995 до 2014 г. е клиничен директор на службата за психично здраве на деца и юноши (CAMHS) в Излингтън, Лондон. В момента д-р Фугъл е клиничен директор в Националния център за деца и семейства „Анна Фройд“ в Лондон и ръководител на Програмата за подобряване на достъпа на деца и млади хора до психологически терапии (CYP-IAPT), финансирана от Националната здравна служба (NHS).
Програмата има за цел да създаде насоки за цялостна трансформация на услугите, насочени към психичното здраве на децата и подрастващите, да повиши качеството на тези услуги, като разшири използването на практики, основани на доказателства, като създаде условия за пълноценно участие на децата, родителите и общността в тях и намали стигмата върху психичното страдание.
Питър Фугъл беше в България през октомври по покана на Ноу-хау центъра за алтернативни грижи за деца към Нов български университет и се включи в поредица от събития. Той взе участие в експертната дискусия за работа с деца и семейства в риск, организирана в София от европейската мрежа Eurochild.
Лекцията на Питър Фугъл пред български експерти от сферата за закрила на деца и специалисти по психично здраве формално трябваше да представи иновативен подход за здравно-социална подкрепа на семейства, в които има родител или дете със зависимост. Когато терапевтът заговори обаче, още от първите му думи стана ясно, че това няма да е формално представяне на един инструмент, а задълбочен човешки разговор как група специалисти в Англия се опитват да върнат фокуса на комплексните здравно-социални услуги там, където уж изначално следва да е насочен – към нуждите на детето и семейството.
Разговорът трябва да започне от възстановяване на доверието на всички нива,
сподели Фугъл с българските си колеги в самото начало. И продължи:
„Една от темите, които забелязах в дискусиите между експертите тук, беше недоверието: недоверие между семействата и професионалистите, недоверие между децата, семействата и други хора, както и недоверие между институциите, които би трябвало да ги подкрепят.
Усилията за справяне с това всепроникващо недоверие стоят в основата на модела, който разработихме, особено с недоверието между институциите, с което се сблъскваме и в Англия. То беше толкова дълбоко, че срещнахме повече трудности в преодоляването на недоверието между институциите и насърчаването на взаимното им сътрудничество, отколкото между младите хора и възрастните. В Англия също сме изправени пред значителни предизвикателства, не сме разрешили много проблеми, затова съм тук не да натрапвам готови решения, а да представя нашите търсения и идеи.“
Една от целевите групи, с които екипът на Питър Фугъл работи, са деца, в чиито семейства има проблем със злоупотребата с вещества. Може да е някой от родителите, но може да е и самото дете. В Англия това са 5% от семействата, в САЩ са 10%. За България количествени данни липсват. Но не само. У нас по отношение на хората, които употребяват различни вещества или развиват зависимости, все още се използва терминология, която в голямата си част не е синхронизирана с научния апарат на съвременната медицина и психология. А думите имат значение, подчерта Питър Фугъл:
„По въпроса за злоупотребата с алкохол или вещества от страна на родителите забелязах непоследователния език, който се използва тук. Зависимостта е малка част от разстройството, свързано със злоупотреба с вещества. В момента именно този термин е по-често употребяван и широко разпространен.
Някой може да пие редовно и да функционира напълно нормално. За разстройство говорим, когато това компрометира функционирането му, а при хората, които имат деца – когато е нарушена способността им да бъдат родители. Тази разлика е от съществено значение, защото насочва фокуса ни от степента на употреба към влиянието ѝ върху личността. Именно там се срещат интересът на здравната система към родителя и неговия психично-здравен проблем и интересът на системата за закрила към благополучието на детето.“
Спорeд Фугъл за проблеми, които засягат различни аспекти от човешкия живот – какъвто например е проблемната употреба, – трябва да има ясна и общоприета дефиниция, с която да боравят всички подкрепящи услуги:
Тази дефиниция води до втория ключов момент: решаването на проблема със злоупотребата с вещества не се ограничава до самия него, а включва и свързани въпроси – жилищни условия, управление на финансите, дългове и хазарт, насилие в семейството и др. Тези свързани проблеми влияят на функционирането на засегнатия човек и цялото му семейство, затова и изолираното третиране само на злоупотребата с вещества е невъзможно.
Във Великобритания има около 100 000 деца под закрила, като броят им се е увеличил значително след COVID-19, разказа Питър Фугъл. При около 60% от тях злоупотребата с вещества е част от семейния фон. Специалистът обясни, че макар привидно ситуациите често да са сходни, индивидуализираният подход е от съществено значение:
„Конфигурацията на проблемите в едно семейство е уникална. Въпреки че има случаи, когато зависимостта или тежките проблеми с веществата са основната грижа, това е по-рядко срещано, отколкото си представяте. Най-често ключът е в комбинацията от множество проблеми, усложняващи предизвикателствата пред семейството, затова и стратегиите за подкрепа трябва да целят да помогнат на засегнатия човек и семейството му да функционират по-добре, а не само да лекуват злоупотребата с вещества.“
В търсене на по-добри решения екипът на Питър Фугъл разработва метод за работа с хора, засегнати от проблемна употреба, и го прилага при деца и младежи в риск да бъдат отделени от семейството им. Методът цели да помогне на младежите да опознаят по-добре себе си, да разберат кои са силните им страни и да подобрят усещането за справяне с проблемите. Влиянието върху употребата би било част от ефекта, когато се постигне успех, но не е основна цел.
Целта е подобряване на благосъстоянието на човека, подчерта Питър Фугъл.
Работихме с младеж, който не виждаше себе си като човек с психични проблеми. Той не ходеше на училище, имаше напрегнати отношения с майка си и понякога употребяваше канабис. Идеята да се включи в услуга за психично здраве беше немислима за него.
Момчето имаше доверие на своя треньор по футбол – единствения стабилен възрастен в живота му. Когато се свързахме с треньора, той първоначално каза: „Аз не се занимавам с психично здраве, разбирам само от футбол.“ Но след няколко разговора се съгласи да помогне. Премина кратко обучение и с напътствия от нас стана мост между младежа и нашата услуга.
Един ден младежът се съгласи да се срещне с мен, защото треньорът му беше казал, че макар самият той да не вярва на психолози, на мен ми има доверие. Това промени нещата и отвори вратата за подкрепа към това момче. Младият човек в крайна сметка се включи в разговори с нас не защото търсеше помощ, а защото за първи път се почувства уважен и чут.
Тази история илюстрира ключовата роля на доверието, подчерта Фугъл. То често трябва да дойде от човек, на когото младежът вече се доверява, вместо някой специалист да се опитва да изгражда доверие от нулата, както работят традиционните услуги:
„Недоверието не е психично разстройство. То е индикация за преживяванията, които човек е имал в живота си. Ако искаме наистина да помогнем на един млад човек, трябва да се водим от въпроса защо той не ни се доверява, а не от усилието да преодолеем недоверието му. Трябва да бъдем любопитни към тези деца, да се опитаме да си представим през какво са преминали, за да станат такива, каквито са, и как се чувстват в момента, в който ние се срещаме със случая им.
и всъщност не е труден, всички ние го правим инстинктивно във всекидневието си. Просто тук, в работата, усилието да си представим мисловността на човека, на когото искаме да помогнем, е съзнателно и е ключова част от нашия инструментариум. Клиентът ви винаги ще усети искреното ви усилие да се поставите на негово място, да го разберете.“
Водени от тази идея, специалистите от Националния център за деца и семейства „Анна Фройд“ в Лондон разработват подхода „Интегративно лечение, базирано на адаптивна ментализация“, или AMBIT (Adaptive Mentalization Based Integrative Treatment). Това сложно за неспециалистите наименование обозначава комплексен подход, в центъра на който стоят хора с множество признаци на уязвимост и силно недоверие в системите за подкрепа:
Младите хора, на които ние искаме да помогнем, най-често не търсят помощ. Затова и помощта не се предоставя от един човек или екип, а чрез мрежа от взаимоотношения. Когато използваме този подход, откриваме, че около младежа най-често има някой стабилен възрастен, но той не се разпознава веднага от професионалистите. Предизвикателството е да се включат и оценят тези неформални опори, защото те са изключително важни.
Питър Фугъл представи и друг аспект на AMBIT – работата с професионалистите, които трябва да подкрепят даден младеж. От една страна, те трябва да развият доверието помежду си, а от друга – да получават подкрепа, за да запазят собственото си психично здраве.
„Както ви споменах в началото, и в Англия сериозен проблем беше да убедим специалистите от различни сфери да си взаимодействат и да си имат доверие. Едно изследване например показа, че здравните специалисти, които лекуват възрастни със зависимости, нямат и не събират информация дали тези пациенти са родители. А това е ключова част от картината. Затова ние създадохме екипи, които включват социални работници, учители или специалисти по приобщаващо образование, специалисти по психично здраве и по злоупотреба с вещества.
Този интегриран модел насърчава сътрудничеството и води до по-добри резултати за семействата. Неформалните взаимоотношения между членовете на екипа, изградени чрез споделени разговори и взаимно доверие, всъщност са по-ефективни от официалните обучения. Това увеличава и взаимната им подкрепа, защото хората в тези професии са подложени на огромен стрес и тревожност. И ако понякога човек е тревожен, че не знае какво да прави, в системата за закрила професионалистите нерядко са тревожни, защото знаят какво се случва, знаят какво да правят, знаят и какви са рисковете, и какъв е залогът.“
Любопитно и важно откритие на екипа на център „Анна Фройд“ е, че обединяването на здравната и социалната подкрепа за хора с проблемна употреба и техните семейства в една комплексна услуга е и икономически ефективно. Според Питър Фугъл при новия модел общите разходи за услуги за защита намаляват със значителни суми:
Знам, че това е ключов въпрос, когато трябва да убедите властите в нещо. Първоначално звучи сложно и скъпо да добавите специалисти по психично здраве в екипи, които се занимават със социална работа. Установихме обаче, че тази инвестиция се изплаща за около три месеца.
В Англия 25% от семействата, които са насочени към службите по психично здраве, изобщо не се появяват на определените им консултации. Социалните работници полагат огромни усилия и отделят работно време, равняващо се на милиони паунди, за да направят оценка, да уредят срещите им със специалисти по психично здраве, после да ги посещават, за да разберат защо не са се явили на тези срещи… Огромен труд, който не помага на никого.
Наред с другото специалистите по психично здраве в екипа помагат да се идентифицира помощта, която наистина да е полезна на конкретния човек и конкретното семейство. Според Питър Фугъл, въпреки всички предизвикателства, недостатъчни ресурси и кадри, този подход показва, че ако специалистите работят взаимосвързано, с доверие и с истинска любознателност относно нуждите на младежите и семействата им, това води до устойчива промяна:
„Ние често смятаме, че знаем от каква помощ има нужда уязвимият човек. И или не питаме хората, или ги питаме в неподходящ етап от работата си с тях от какво смятат, че имат нужда. Това не е някакъв тривиален въпрос, който можем да обсъдим мимоходом, а може би най-трудната задача в процеса. Какво младежите и родителите смятат, че би им помогнало? Понякога става дума за подкрепа, която просто да подобри функционирането им. За един специалист невинаги е лесно да приеме, че може да помогне на човек с проблемна употреба, без изобщо да се занимава със самата употреба.“
В рубриката „Разговори за здравеопазването“ Надежда Цекулова кани своите събеседници да поговорят без клишета и празнодумие за проблемите и решенията, болката и оздравяването, медицината и политиката.
Post Syndicated from Sophie Ashford original https://www.raspberrypi.org/blog/celebrating-the-community-prabhath/
We love hearing from members of the community and sharing the stories of amazing young people, volunteers, and educators who are using their passion for technology to create positive change in the world around them.
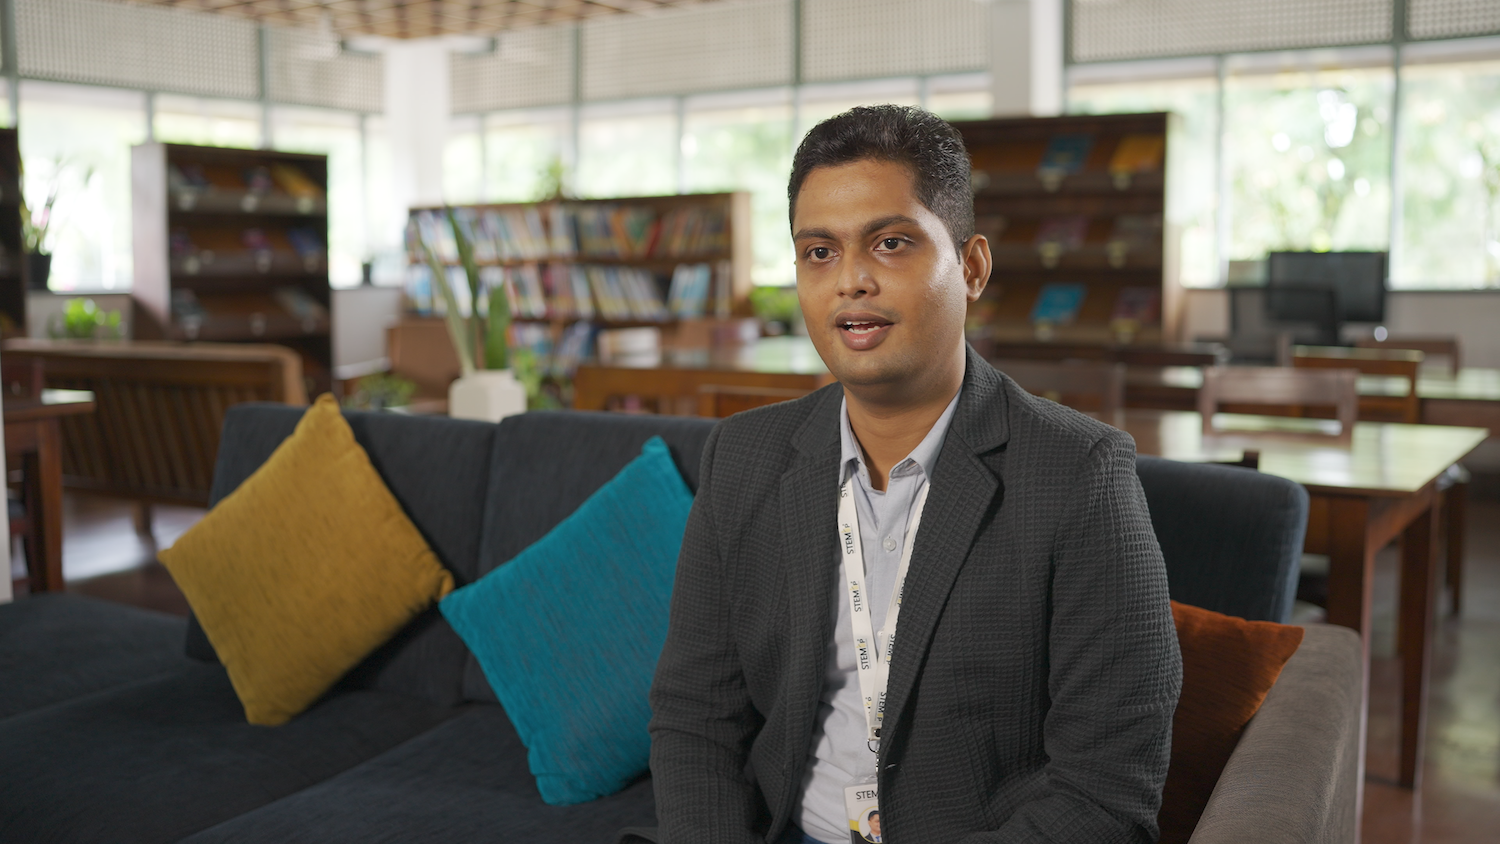
Prabhath, the founder of the STEMUP Educational Foundation, began his journey into technology at an early age, influenced by his cousin, Harindra.
“He’s the one who opened up my eyes. Even though I didn’t have a laptop, he had a computer, and I used to go to their house and practise with it. That was the turning point in my life.”
This early exposure to technology, combined with support from his parents to leave his rural home in search of further education, set Prabhath on a path to address a crucial issue in Sri Lanka’s education system: the gap in opportunities for students, especially in STEM education.
“There was a gap between the kids who are studying in Sri Lanka versus the kids in other developed markets. We tried our best to see how we can bridge this gap with our own capacity, with our own strengths.”
Recognising the need to close this gap in opportunities, Prabhath, along with four friends who worked with him in his day job as a Partner Technology Strategist, founded the STEMUP Educational Foundation in 2016. STEMUP’s mission is straightforward but ambitious — it seeks to provide Sri Lankan students with equal access to STEM education, with a particular focus on those from underserved communities.
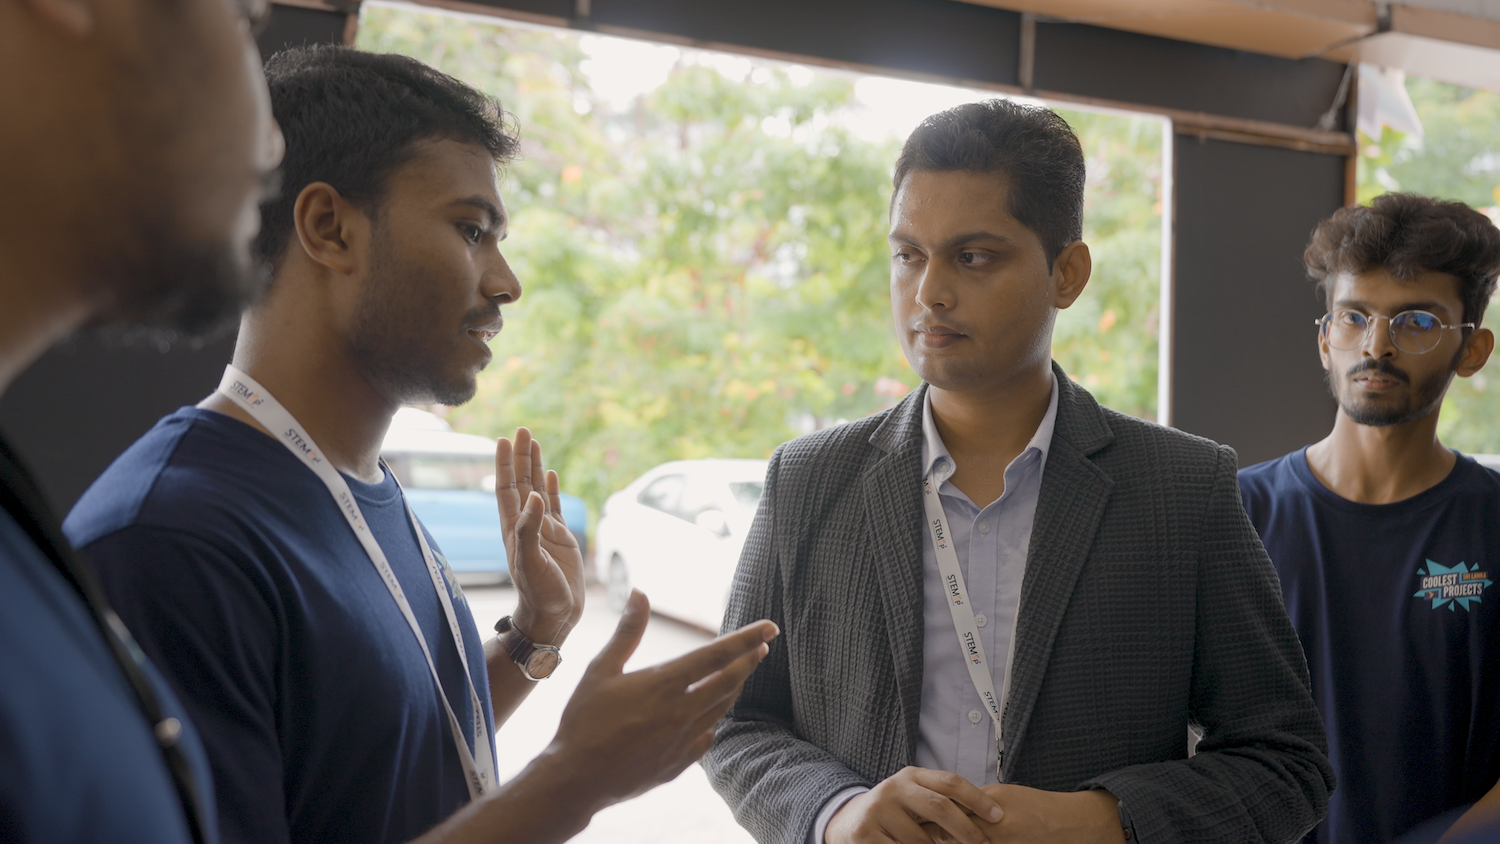
To help close the gap, Prabhath and his team sought to establish coding clubs for students across the country. Noting the lack of infrastructure and access to resources in many parts of Sri Lanka, they partnered with Code Club at the Raspberry Pi Foundation to get things moving.
Their initiative started small with a Code Club in the Colombo Public Library, but things quickly gained traction.
What began with just a handful of friends has now grown into a movement involving over 1,500 volunteers who are all working to provide free education in coding and emerging technologies to students who otherwise wouldn’t have access.
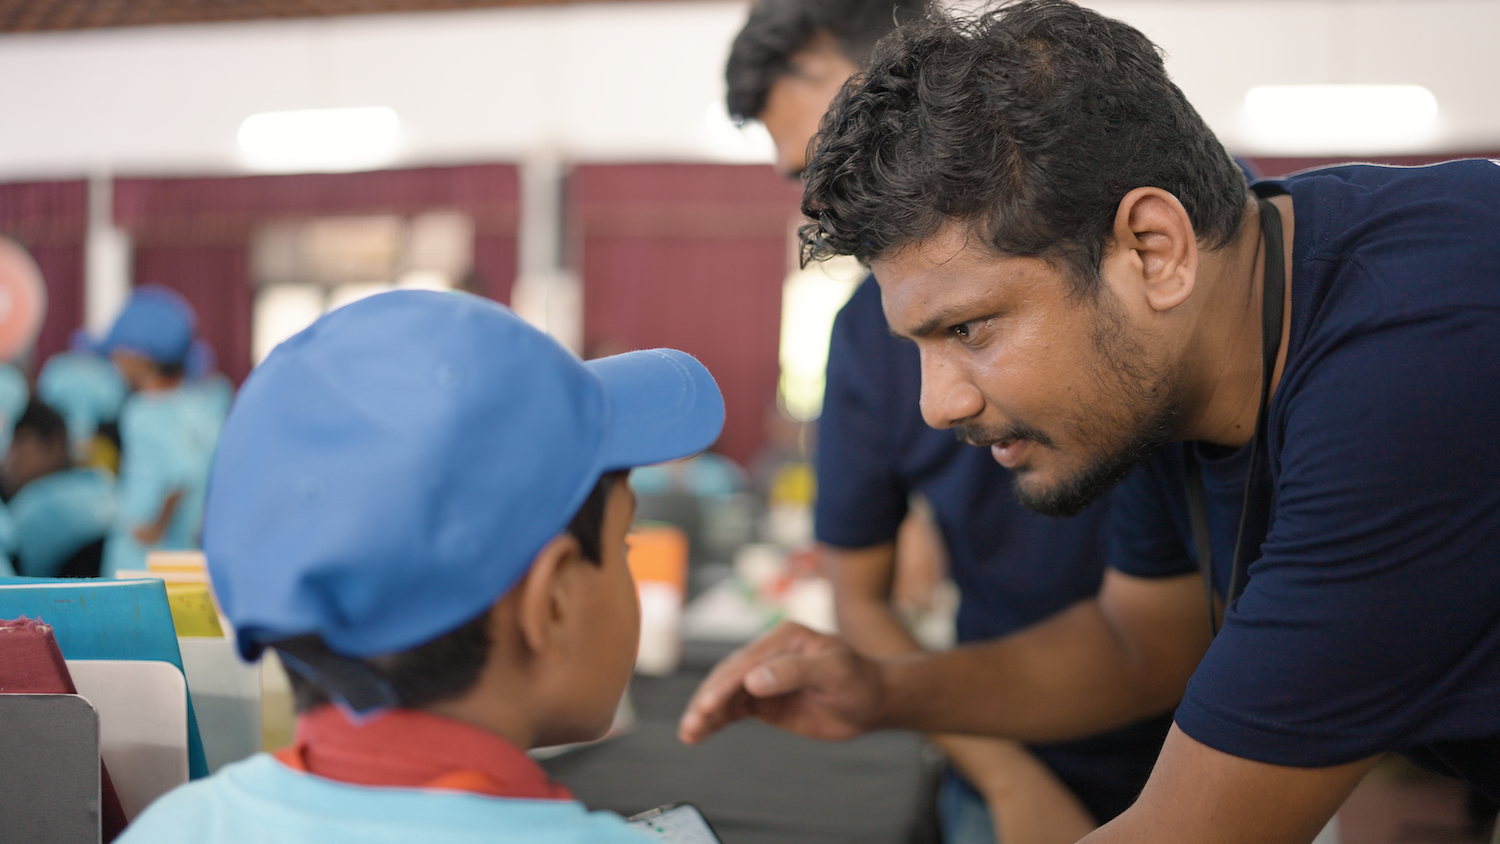
A key reason for STEMUP’s reach has been the mobilisation of university students to serve as mentors at the Code Clubs. Prabhath believes this partnership has not only helped the success of Code Club Sri Lanka, but also given the university students themselves a chance to grow, granting them opportunities to develop the life skills needed to thrive in the workforce.
“The main challenge we see here today, when it comes to graduate students, is that they have the technology skills, but they don’t have soft skills. They don’t know how to do a presentation, how to manage a project from A to Z, right? By being a volunteer, that particular student can gain 360-degree knowledge.”
STEMUP’s impact stretches beyond cities and into rural areas, where young people often have even fewer opportunities to engage with technology. The wish to address this imbalance is a big motivator for the student mentors.
“When we go to rural areas, the kids don’t have much exposure to tech. They don’t know about the latest technologies. What are the new technologies for that development? And what subjects can they study for the future job market? So I think I can help them. So I actually want to teach someone what I know.” – Kasun, Student and Code Club mentor
This lack of access to opportunities is precisely what STEMUP aims to change, giving students a platform to explore, innovate, and connect with the wider world.
STEMUP recently held the first Coolest Projects Sri Lanka, a showcase for the creations of young learners. Prabhath first encountered Coolest Projects while attending the Raspberry Pi Foundation Asia Partner summit in Malaysia.
“That was my first experience with the Coolest Projects,” says Prabhath, “and when I came back, I shared the idea with our board and fellow volunteers. They were all keen to bring it to Sri Lanka.”
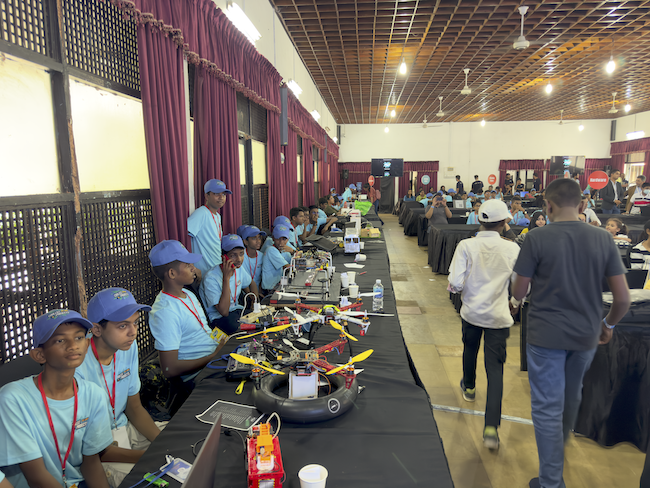
For Prabhath, the hope is that events like these will open students’ eyes to new possibilities. The first event certainly lived up to his hope. There was a lot of excitement, especially in rural areas, with multiple schools banding together and hiring buses to attend the event.
“That kind of energy… because they do not have these opportunities to showcase what they have built, connect with like minded people, and connect with the industry.”
Looking ahead, Prabhath sees STEMUP’s work as a vital part of shaping the future of education in Sri Lanka. By bringing technology to public libraries, engaging university students as mentors, and giving kids hands-on experience with coding and emerging technologies, STEMUP is empowering the next generation to thrive in a digital world.
“These programmes are really helpful for kids to win the future, be better citizens, and bring this country forward.”
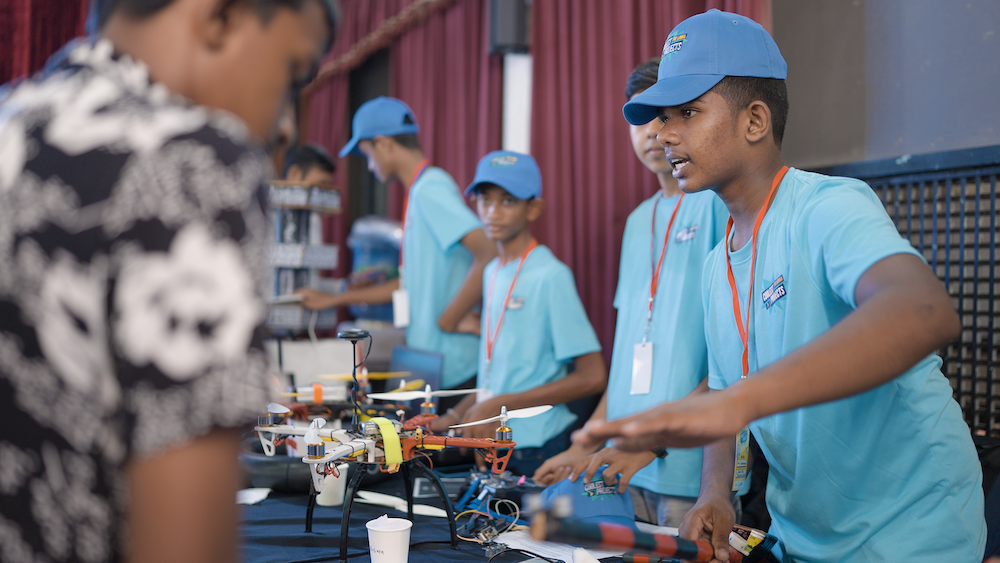
STEMUP is not just bridging a gap — it’s building a brighter, more equitable future for all students in Sri Lanka. We can’t wait to see what they achieve next!
To find out how you and young creators you know can get involved in Coolest Projects, visit coolestprojects.org. If the young people in your community are just starting out on their computing journey, visit our projects site for free, fun beginner coding projects.
For more information to help you set up a Code Club in your community, visit codeclub.org.
Help us celebrate Prabhath and his inspiring journey with STEMUP by sharing this story on X, LinkedIn, and Facebook.
The post Celebrating the community: Prabhath appeared first on Raspberry Pi Foundation.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=fFxdN9gJqbI
Post Syndicated from xkcd.com original https://xkcd.com/3012/