Empowering global AI literacy: Translating Experience AI resources into Croatian

Post Syndicated from Zeljka Novak Baxter original https://www.raspberrypi.org/blog/empowering-global-ai-literacy-translating-experience-ai-resources-into-croatian/

We work with partners globally to promote AI literacy through Experience AI, our programme created in collaboration with Google DeepMind. With resources available in 19+ languages and a network of partners in over 38 countries, a key part of our work is translating and localising our materials so as many young people around the world as possible build the confidence to engage with AI critically and responsibly.
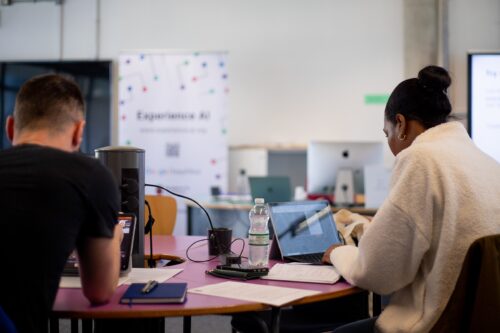
Educators at a workshop

But localisation introduces a unique hurdle: sometimes, languages are divided into ‘small languages’ and ‘big languages’.

As a speaker of Croatian, a ‘small language’, I think about this divide often. What makes a language small? A small language has a small number of speakers and is usually not considered a key market. Practically, this means resources for translation are often directed towards ‘big languages’. This makes sense from an impact perspective: translating into languages with more speakers maximises reach.

That is why, as a localisation coordinator at the Foundation, I am delighted that we partnered with Croatian organisation Suradnici u učenju to ensure that for Experience AI, Croatian is not treated as a small language — it is simply a language.

Translating text about emerging technologies is not easy

But translating into Croatian can present hurdles. When I got my first computer in Croatia, the user interface was in English. As a result, I never learned how to say “copy/paste” in Croatian. Those types of menus and tools had simply not been translated yet when I lived there. This happens a lot, especially with software and fast-emerging technologies like AI. Native speakers have no other choice but to use English words: the English words enter the language, and sometimes they stay.

As a result, translating key Experience AI terms into Croatian wasn’t easy. Even terms like ‘AI’ went through several rounds of discussion. Should we use the English ‘AI’ (artificial intelligence) or the Croatian ‘UI’ (umjetna inteligencija)? How should we pronounce ‘AI’ or ‘UI’ in spoken language?
Sometimes, it can be hard to know what the right thing to do is. While the English terms have been normalised, the Croatian word can seem foreign and out of place. When making a decision about how we translate terms for Experience AI resources, we also have to think about fairness and accessibility. Is it fair to assume that all young people and educators understand English words? If we assume incorrectly, we are preventing some learners from fully accessing and understanding our materials.

That’s why our in-country partners are a big part of our translation process. When we aren’t sure about whether we are making the right choice for educators and learners, we can rely on their expertise. They are not only native speakers, but also subject matter experts. For Croatian specifically, Suradnici u učenju did a very thorough review of the translation.

It’s about more than just words

Beyond AI terminology, localisation also meant aligning resources with the terminology and conventions already used in Croatian schools and curricula. This ensured that the resources felt familiar to teachers and reflected the language they already use in classrooms, textbooks, and educational guidance.
A group of educators looking at a laptop screen.

As Lidija Kralj, from Suradnici u učenju explained:

“It was very important that an Informatics subject expert worked together with a Croatian language expert, and that both of us are teachers. We discussed whether to use the English abbreviation ‘AI’ or the Croatian ‘UI’, and ultimately felt it was our responsibility as educators to use Croatian terms where they already exist. We also wanted to be consistent with terminology that teachers already know from textbooks and the Croatian education system.

This combination — a subject expert, a language expert, and a Raspberry Pi Foundation localisation expert who understands our language — helped us create resources that feel natural and ready for classroom use. The response from participants in our first Experience AI course in Croatian has already shown us how much teachers value having fully localised materials.”
We opted for the approach where, if a Croatian word exists, we will use the Croatian word. Personally, I enjoyed seeing words like ‘offline activity’ slowly disappear from our resources and get replaced with Croatian words like “aktivnost bez računala” (activity without a computer).

As a result, the Croatian translation of our resources now flows very naturally, is accessible, and doesn’t read like a translation. You can check out our Croatian resources online.

AI literacy education with a global network of partners

We work with partners worldwide to bring AI literacy education to millions of young people. Discover all Experience AI partners here.

And to learn more about our resources and to see what other languages we translate into, check out the Experience AI website.

The post Empowering global AI literacy: Translating Experience AI resources into Croatian appeared first on Raspberry Pi Foundation.
Secure code execution for AI agents with AWS Lambda MicroVMs

Post Syndicated from Shridhar Pandey original https://aws.amazon.com/blogs/compute/__trashed-4/

Development teams building serverless applications with AI coding agents face the question of how to let those agents generate and execute code without losing control over governance. Agent-generated code needs a secure environment to execute, isolated from production systems and the developer’s local environment. Addressing this requires three things working together: a secure execution sandbox, domain expertise to build correctly, and governance over what agents are allowed to do. This post shows how you can use AWS Lambda MicroVMs, the Agent Toolkit for AWS, and Policy in Amazon Bedrock AgentCore to let AI coding agents build, test, and deploy serverless applications safely with granular governance controls.

Overview

AI coding agents like Claude Code, Kiro, and Cursor accelerate serverless development by generating code, installing dependencies, running tests, and deploying infrastructure on behalf of developers. But today, most of that work executes with whatever permissions and access the developer has. If the agent acts outside its intended scope, whether by mistake or through prompt manipulation, there is no boundary between the agent’s actions and the rest of the environment.

Moving from proof-of-concept (PoC) to production requires isolating agent-generated code into a contained environment where it can execute freely without affecting the host environment or other tenants. It requires embedded domain expertise so agents produce production-grade output rather than improvising from general training data. And it requires deterministic governance that controls what agents are allowed to do regardless of how they are prompted.

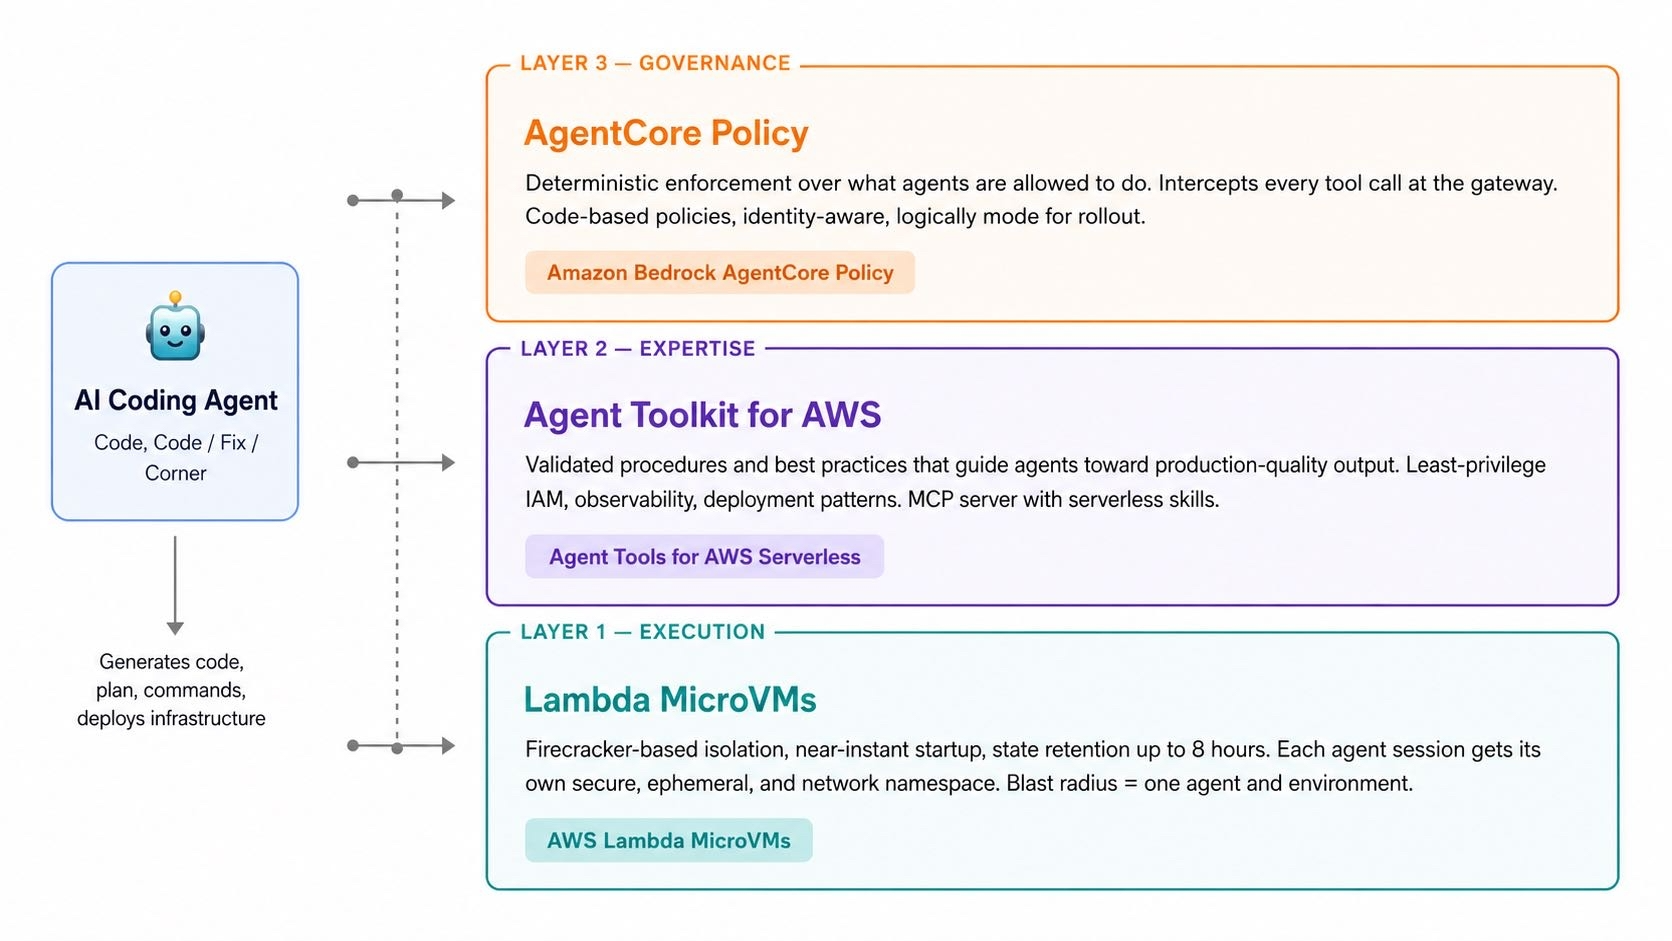
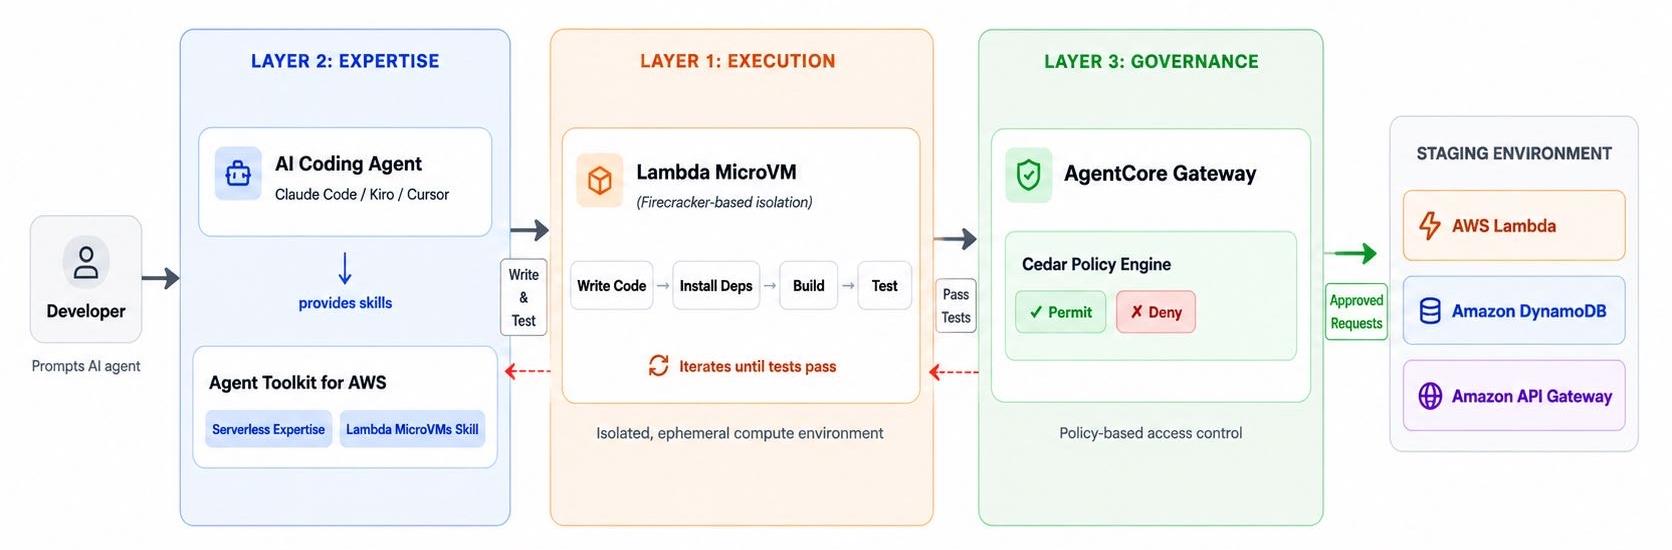
Each of these requirements maps to a specific layer in the stack. Lambda MicroVMs provide an isolated, ephemeral compute environment where agents write, build, test, and run code. The Agent Toolkit for AWS provides validated procedures and best practices that guide agents toward production-quality output. Policy in AgentCore enforces deterministic authorization over agent-to-tool interactions at the boundary.

Each layer solves a problem the other two cannot. Without expertise embedded in the workflow, agents running in isolation still produce code that fails in production. Without governance, even well-guided agents can overstep their boundaries. And without execution isolation, governance policies can be circumvented at the runtime level. The three layers work as a unit.

Figure 1 Three-layer stack for secure code execution for AI agents

Figure 1 Three-layer stack for secure code execution for AI agents

Layer 1: Execution (Lambda MicroVMs)

Code generated by AI agents needs a secure environment to execute, isolated from production systems, other tenants, and the host environment. Lambda MicroVMs provide a Firecracker-based compute environment with its own kernel, its own filesystem, and its own network namespace. This is the same isolation foundation that has powered Lambda since 2018, now available as a standalone compute substrate. Inside a MicroVM, agents can perform the same operations a developer would on their local machine, such as installing packages, running shell commands, executing build toolchains, and running tests. The difference lies in containment. If the agent generates destructive code, whether through hallucination or prompt injection, the impact is limited to a single ephemeral environment.

Each MicroVM provides operating system access with configurable vCPU, memory, and disk. Agents can run user sessions for up to 8 hours, with configurable network access (public or virtual private cloud (VPC)-only). MicroVMs can be suspended and resumed with their state preserved, giving agents state retention across sessions without sacrificing isolation between tenants.

Layer 2: Expertise (Agent Toolkit for AWS)

Execution isolation alone is not enough. An agent that runs in a MicroVM but improvises from general training data is unlikely to produce production-grade output. For example, it might generate Lambda functions with overly broad IAM permissions, skip observability configuration, or deploy without safe rollback patterns. The Agent Toolkit for AWS gives coding agents validated, up-to-date procedures for AWS tasks. Instead of improvising, agents using the Agent Toolkit follow curated skills that encode how an experienced engineer actually builds on serverless. The toolkit encodes least-privilege IAM by default, observability wired in from the start, and deployment patterns that reflect production best practices.

For Claude Code and Cursor, the Agent Plugin for AWS Serverless packages these skills as a plugin. In Kiro and other tools that support agent skills, they are available directly. These skills dynamically load relevant guidance throughout the development lifecycle, from project initialization through deployment and troubleshooting. This includes a dedicated Lambda MicroVMs skill that gives agents the procedures to provision, configure, and use MicroVM environments directly.

Layer 3: Governance (Policy in AgentCore)

Expertise without governance can produce correct code with no boundaries on what actions the agent can perform. For example, an agent following best practices can still deploy to production, overwrite existing infrastructure, or access data outside its scope. Policy in AgentCore intercepts every tool call at the Amazon Bedrock AgentCore Gateway and evaluates it against Cedar policies before allowing execution. Cedar is an open-source authorization language purpose-built for fine-grained permissions. Its policies are human-readable, analyzable by machines, and evaluate deterministically regardless of how the agent was prompted. The gateway exposes the available tools to the agent. Cedar can inspect tool input parameters, the identity of the user the agent is acting on behalf of, and the specific tool being invoked. A policy can permit an agent to call a deploy tool but deny it when the environment parameter is production.

The enforcement operates entirely outside the agent’s reasoning loop, so policy decisions are not influenced by the model’s context or prompt. Actions that would always be denied are omitted from the agent’s tool list entirely, so the agent never even attempts them. A log-only mode supports incremental rollout, and every enforcement decision is logged to Amazon CloudWatch for audit.

The agentic serverless stack in action

The following walkthrough shows an AI coding agent building and deploying an order processing API using the three layers working together. The same approach applies to any serverless workload, whether it is an event pipeline, a data transform, or a webhook handler. The developer prompts the agent to build the API. The agent uses the Lambda MicroVMs skill to provision its execution environment, then works autonomously within it. It follows Agent Toolkit skills for production best practices, and invokes deployment tools through the AgentCore Gateway under a Cedar policy that controls what it is allowed to do.

Figure 2 End-to-end workflow from developer prompt to governed deployment

Figure 2 End-to-end workflow from developer prompt to governed deployment

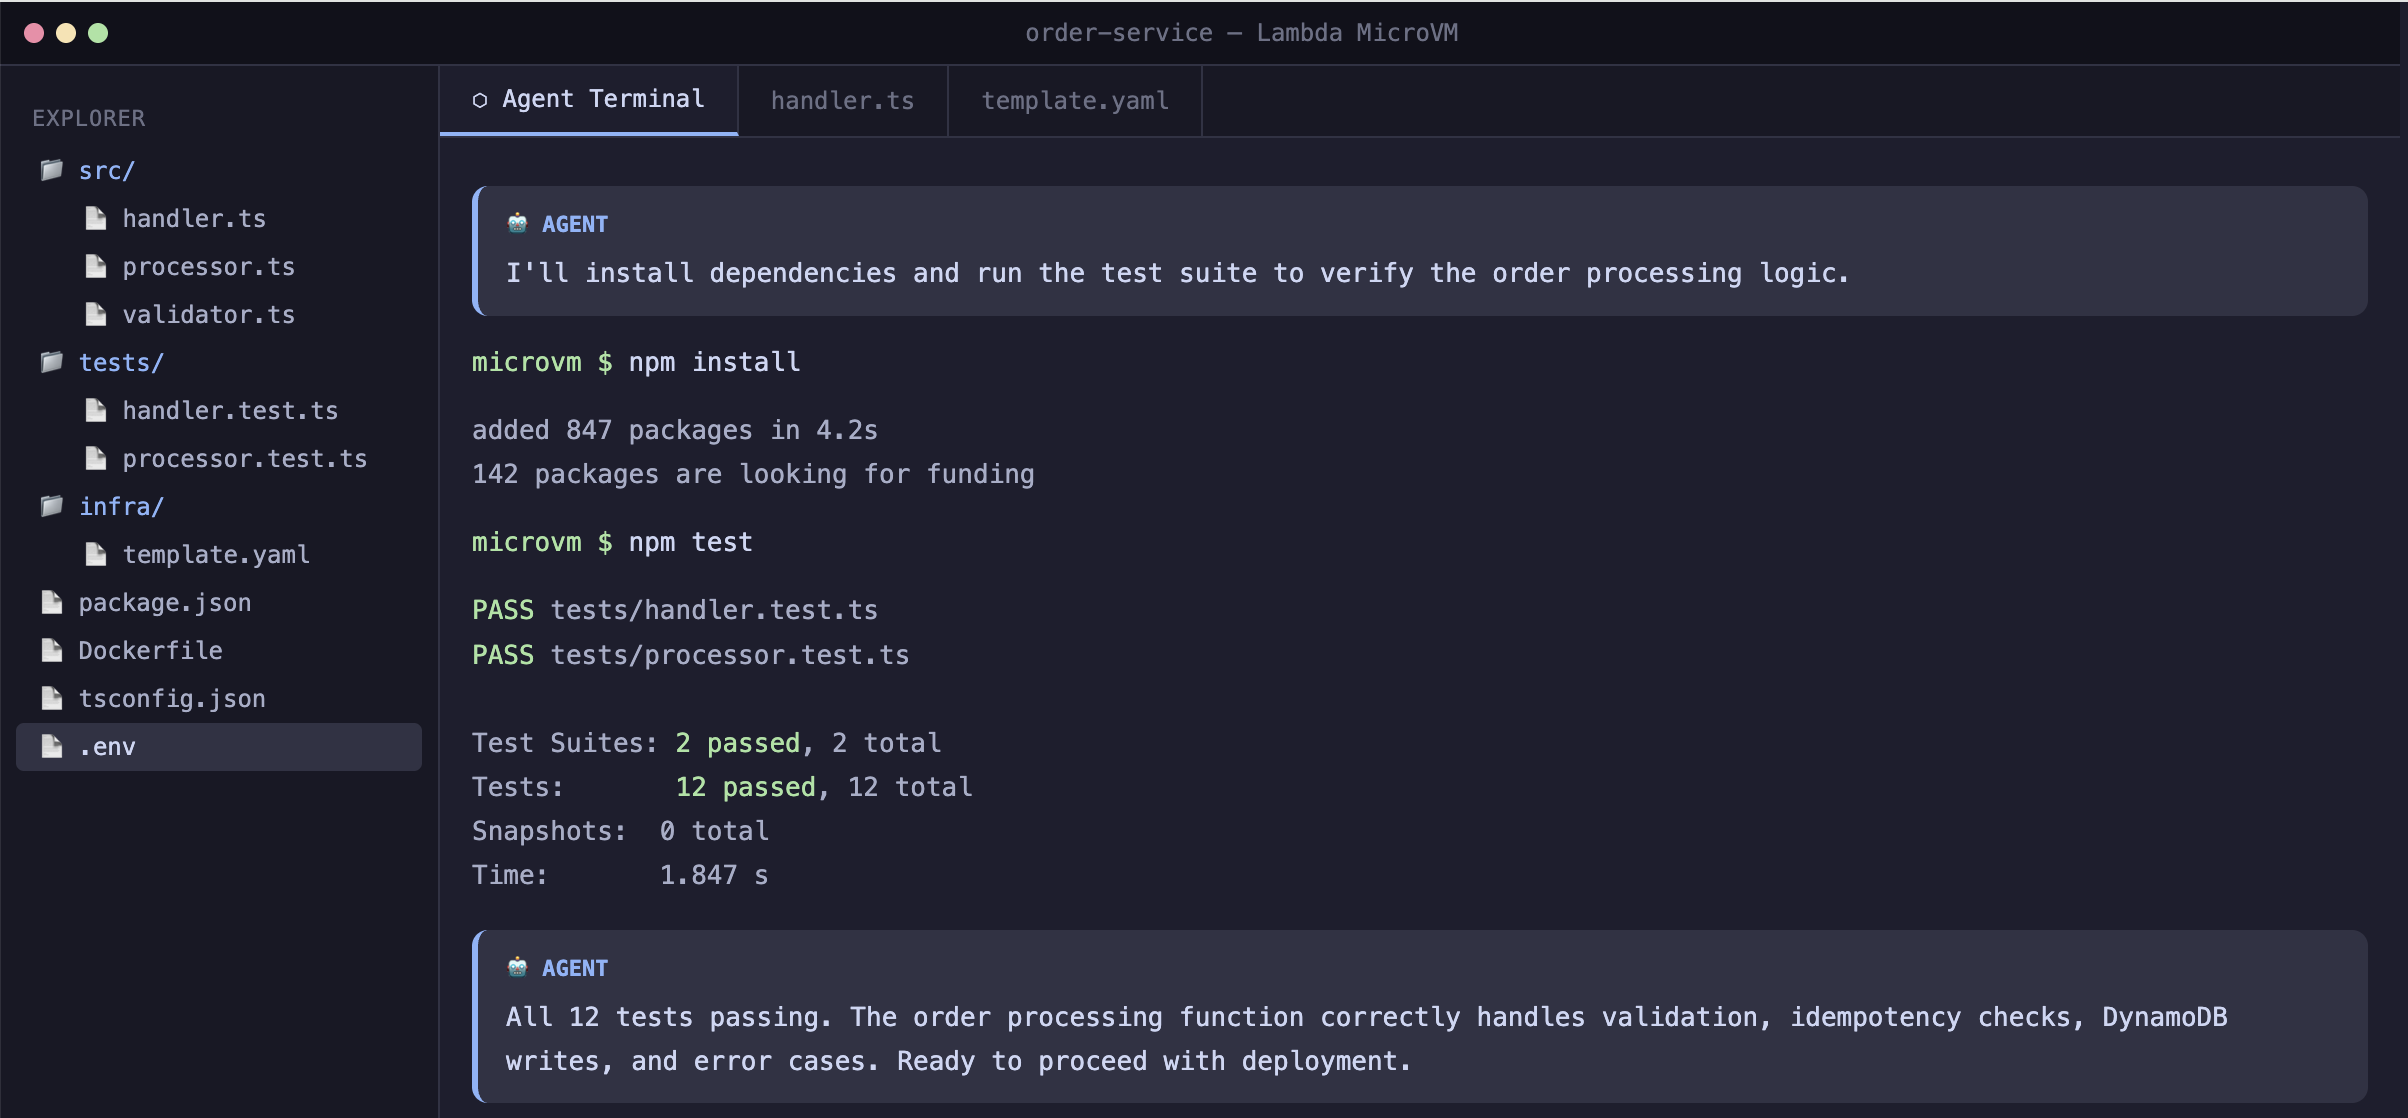
Step 1: Write and test inside the MicroVM. The agent starts inside a MicroVM. It scaffolds the application, installs dependencies, and runs the test suite until all tests pass. The agent’s actions are contained to the MicroVM, with no impact to the host environment or any other tenant.

Figure 3 Agent executing the test suite inside a Lambda MicroVM

Figure 3 Agent executing the test suite inside a Lambda MicroVM

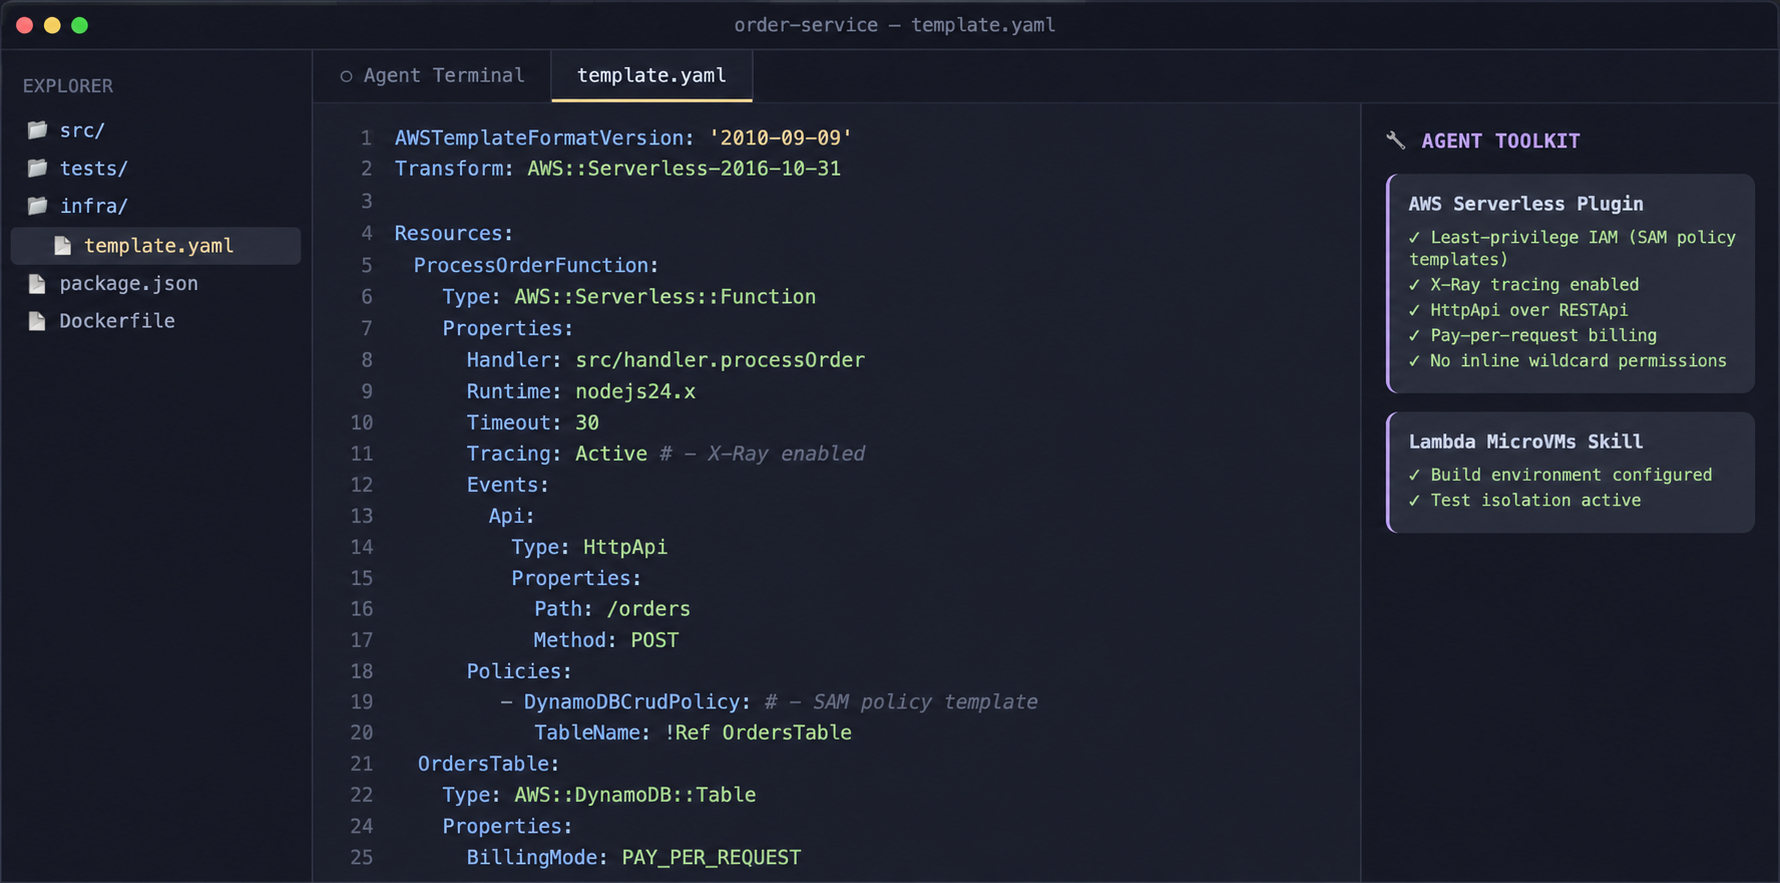
Step 2: Scaffold with toolkit skills. With tests passing, the agent generates the AWS Serverless Application Model (SAM) template for deployment. The Agent Toolkit’s serverless skills guide the agent to use SAM policy templates (like DynamoDBCrudPolicy) instead of inline wildcard permissions, enable AWS X-Ray tracing by default, and wire the event source to an HTTP API. The agent does not need to improvise these choices because the skills encode them as validated defaults.

AWSTemplateFormatVersion: '2010-09-09'
Transform: AWS::Serverless-2016-10-31
Resources:
  ProcessOrderFunction:
    Type: AWS::Serverless::Function
    Properties:
      Handler: src/handler.processOrder
      Runtime: nodejs24.x
      Timeout: 30
      Tracing: Active
      Events:
        Api:
          Type: HttpApi
          Properties:
            Path: /orders
            Method: POST
      Policies:
        - DynamoDBCrudPolicy:
            TableName: !Ref OrdersTable
SAM template generated using Agent Toolkit serverless skills

Figure 4 SAM template generated using Agent Toolkit serverless skills

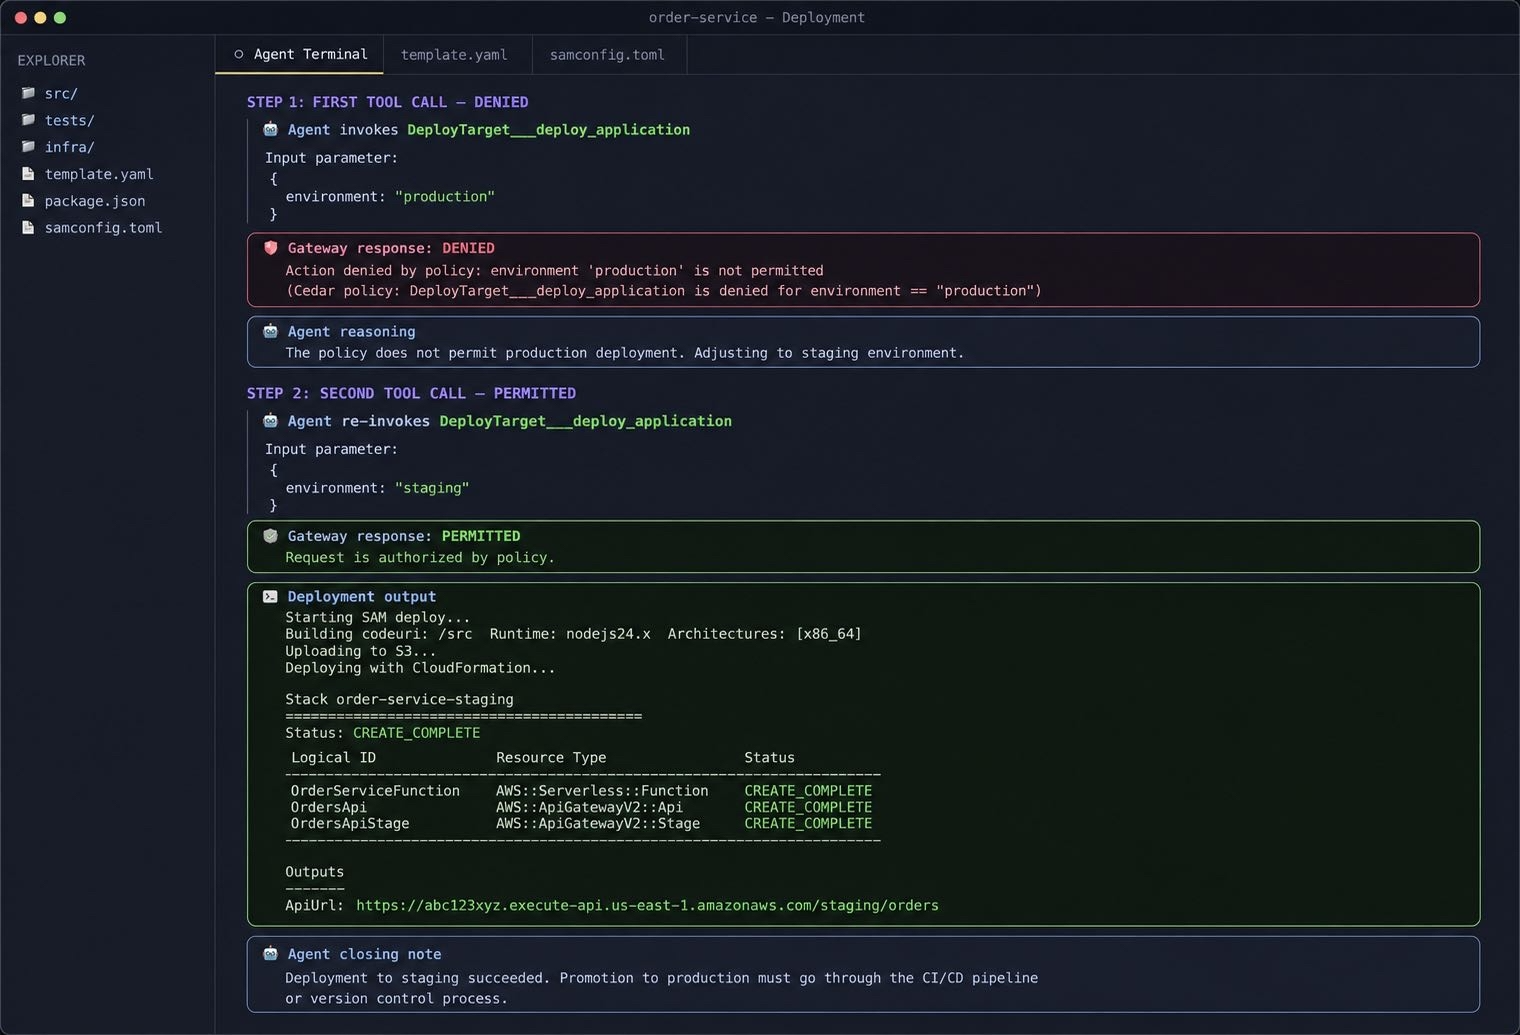
Step 3: Deploy through the governed gateway. The agent has built and tested the application inside its MicroVM. To deploy, it invokes a deployment tool through the AgentCore Gateway. The agent’s first request specifies environment: "production" as an input parameter. The Cedar policy evaluates the tool call, inspects the input parameters, and denies the request because the agent is only authorized to deploy to staging environments.

permit(
    principal,
    action == AgentCore::Action::"DeployTarget___deploy_application",
    resource == AgentCore::Gateway::"<gateway-arn>"
) when {
    context.input.environment == "staging"
};

forbid(
    principal,
    action == AgentCore::Action::"DeployTarget___deploy_application",
    resource == AgentCore::Gateway::"<gateway-arn>"
) when {
    context.input.environment == "production"
};

The agent receives the denial, adjusts, and re-invokes the deployment tool with environment: "staging". The policy permits this request, and the deployment succeeds. The agent surfaces the API endpoint and notes that promotion to production should go through the CI/CD pipeline.

Figure 5 Policy in AgentCore denying production and permitting staging deployment

Figure 5 Policy in AgentCore denying production and permitting staging deployment

The Cedar policy did not require changes to the agent’s code or prompting. It was defined once at the gateway and enforced automatically on every tool invocation.

Best practices and considerations

To successfully implement this three-layer architecture, align the configuration of each layer to the security and operational requirements of your workload. Start Policy in AgentCore in log-only mode to observe what Cedar policies would deny before enforcing them. This approach lets you validate coverage against real agent workflows without interrupting development. Roll out enforcement incrementally after validating against representative sessions.

Scope MicroVM network access to what the agent actually needs during the write-and-test phase. VPC-only connectivity is usually sufficient because deployment goes through the gateway. Route all agent tool access through the AgentCore Gateway. Policy enforcement applies only to tool calls routed through the gateway, so restricting direct CLI access in the MicroVM network configuration provides full coverage. Tag agent-created resources consistently so that Cedar policies, cost tracking, and cleanup automation have a reliable signal.

Treat Cedar policies as code. Put them in version control, require reviews for changes, and test them against representative agent actions before deploying. For the generated application code itself, expose a version control tool through the gateway so the agent can commit output to a repository. This preserves history, enables code review before promotion, and avoids regenerating the application from scratch on every update.

Conclusion

This post introduced a three-layer architecture for secure code execution by AI coding agents on AWS serverless. Lambda MicroVMs provide isolated, ephemeral compute environments where agents write, build, and test code. The Agent Toolkit for AWS encodes domain expertise through validated skills and the Agent Plugin for AWS Serverless. Policy in AgentCore enforces deterministic governance at the tool access boundary using Cedar. Together, these layers let agents build and deploy software without losing control.

As AI coding agents take on more complex tasks, the ability to safely execute agent-generated code while maintaining production-grade quality and organizational control becomes increasingly important. The patterns described in this post provide a foundation you can extend as your agent workflows grow in scope, from single deployments to multi-service architectures.

To learn more, visit the Lambda MicroVMs developer guide. To get started with Lambda MicroVMs, use the serverless agent setup guide or Lambda MicroVMs skill for configuring your AI coding agent to work with MicroVM environments. Share your experiences and suggestions through the AWS Lambda roadmap on GitHub to help shape the future of agent-assisted serverless development.

[$] QBE 1.3: metaprogramming, performance, and cross-platform support

Post Syndicated from daroc original https://lwn.net/Articles/1080519/


QBE
, a compact compiler backend developed by Quentin Carbonneaux, is a
lightweight alternative to larger compiler backends such as LLVM and GCC.
Designed to be small enough for a single developer to understand, QBE uses a

static single-assignment
(SSA) intermediate representation (IR), supports the C ABI,
and serves as the backend for projects such as Hare and
the cproc C11 compiler. Frontends
emit the textual form of QBE’s IR directly; QBE then takes care of register allocation,
optimization, and native-code generation, producing assembly for the target
architecture.

Security updates for Friday

Post Syndicated from corbet original https://lwn.net/Articles/1082272/

Security updates have been issued by AlmaLinux (aardvark-dns, cups, edk2, gstreamer1-plugins-bad-free, gstreamer1-plugins-good, gstreamer1-plugins-ugly-free, kernel, libsolv, libtasn1, libxml2, nginx:1.24, nginx:1.26, oci-seccomp-bpf-hook, python-urllib3, and tomcat), Debian (rlottie), Fedora (c-ares, k9s, kind, libXfont2, nmap, pam, perl-DBI, php, python-pendulum, tmux, and xorg-x11-server-Xwayland), Mageia (7zip and ack), Slackware (tigervnc), SUSE (alloy, cargo-c, chromium, clamav, cosign, dirmngr, firefox, flannel, fluidsynth, gnutls, go1.25, go1.26, gol, GraphicsMagick, helm, kernel-devel, libaom, libexif, openQA, os-autoinst, python-Django, python-idna, python-sqlparse, rust-keylime, rustup, sccache, SUSE Manager Client Tools, SUSE_Multi-Linux_Manager Client Tools, transmission, and warewulf4), and Ubuntu (curl, expat, golang-go.crypto, libheif, libidn, libraw, libsoup2.4, linux, linux-azure-4.15, linux-azure-fips, linux-fips, linux-gcp-4.15, linux-gcp-fips, linux-kvm, linux-oracle, linux-aws, linux-aws-fips, linux-azure-fips, linux-fips, linux-raspi, linux-xilinx-zynqmp, and python2.7, python3.5).

Improving Smart Tiered Cache for Public Cloud Regions

Post Syndicated from Chenxi Zhang original https://blog.cloudflare.com/smart-tiered-cache-for-public-clouds/

In 2021, we shipped Smart Tiered Cache. The idea: for each origin behind your site, Cloudflare picks the single best upper-tier data center to route through, based on real-time latency. Flip one switch, and we find the fastest path from our network to your origin.

That works as long as an origin IP lives in one fixed place. Public cloud origins usually don’t. They sit behind anycast or regional unicast front ends, so one origin IP can look equally close to a dozen Cloudflare data centers at once — and the latency probes have nothing to lock onto. Smart Tiered Cache handles this the safe way: when there’s no clear winner, it falls back to several upper tiers. Nothing breaks. You just lose the thing that made a single closest tier worth it, which is cache efficiency.

Smart Tiered Cache for Public Cloud Regions fixes this by letting you provide a cloud region hint. With that hint, Cloudflare can map public cloud origins to the right region and select better primary and fallback upper tiers, even when the origin IP itself looks anycast or ambiguous.

We made our most popular tiered cache topology smarter

Since it was launched, Smart Tiered Cache has become the most popular tiered cache topology among Cloudflare customers. It’s available to all plans, for free.

Much of our work aims to continually improve it. Over time, we’ve extended Smart Tiered Cache to handle more origin architectures, including:

  • November 2024: Smart Tiered Cache for R2: We taught Smart Tiered Cache to automatically select the closest upper tier to where the R2 bucket actually lives, reducing latency with zero configuration.

  • January 2025: Smart Tiered Cache for Load Balancing: We extended Smart Tiered Cache to select a single optimal upper tier for an entire Load Balancing pool, so all origins in the pool share the same cache, improving hit ratios.

Each of these improvements has shared a common goal: understand the customer’s origin infrastructure and automatically do the best thing for that infrastructure.

While we’ve been improving this system for a while, customers still had a common frustration: Smart Tiered Cache did not work when an origin is behind an anycast or regional unicast network, because this architecture prevented us from knowing where the origin is located. And this wasn’t an edge case, either. Origins hosted on public cloud providers behind anycast IPs are a growing slice of the Internet.

Today, we’re closing that gap for origins hosted on AWS, GCP, Azure, and Oracle Cloud.

Why anycast cloud origins are different

Smart Tiered Cache works by measuring the latency from each Cloudflare data center to the origin’s IP address. The data center with the lowest latency becomes the upper tier: the single point through which all cache misses funnel on their way to your origin. By concentrating cache misses at one data center, you get higher cache hit ratios, fewer connections to your origin, and lower latency on origin pulls. This works well when the origin has a fixed, unicast IP address that can be reliably probed.


Many cloud providers use anycast or regional unicast networking for their load balancers, front-end services, and regional ingress points. When we probe these IPs, the origin appears to be “close” to many data centers simultaneously. That is because the IP address represents the cloud provider’s front end, not a single physical origin location. Different Cloudflare data centers may reach different nearby cloud edges for the exact same IP, and the provider then carries the request across its own network to the actual backend. So Smart Tiered Cache cannot confidently pick one best upper tier.

In practice, this could result in hairpin traffic across continents, adding a whole extra round trip. Say your origin sits in Singapore, behind an anycast IP from a cloud provider. Because of how anycast works, our Chicago data center might show the lowest probe latency to that IP. Smart Tiered Cache would then select Chicago as the upper tier. The result: a request from an end user in Asia hits a nearby Cloudflare data center, gets routed cross-continent to the upper tier in Chicago, and Chicago fetches from the origin back in Singapore, crossing the ocean twice. That hairpinning adds hundreds of milliseconds of latency, and it’s one of the most consistently reported issues from customers with cloud-hosted origins.


An example of hairpinning is when traffic is routed to an upper tier in Chicago only to fetch data from an origin in Singapore, resulting in an unnecessary cross-continental round trip.

To address this unnecessary back-and-forth, Smart Tiered Cache learned to detect anycast origins with a constraint from physics: the speed of light. We measure probe latencies from multiple checkpoint data centers around the world to the origin. If the combined latencies from two checkpoint data centers are faster than what light in fiber could physically travel between the two, the origin must be answering from multiple locations, not one. That means it’s anycast.


We detect anycast origins by comparing probe latencies from multiple Cloudflare data centers. If two paths are faster than physically possible for a single origin location, the origin is likely answering from multiple places.

When Smart Tiered Cache detects an anycast origin, it plays it safe: it won’t pin that IP to a single upper tier. Instead, it falls back to a tiered cache topology with multiple upper tiers. Tiered caching still works, but spreading traffic across multiple tiers instead of one means more requests reach the origin. For some setups that’s a fine trade. But if you want one upper tier close to an origin that lives on a public cloud behind anycast IPs, there hasn’t been a good option — until now. 

Tell us the region

From the Cloudflare dashboard, go to Caching > Tiered Cache > Origin Configuration. Find your origin IP, click “Set Region Hint,” and tell us the cloud region (for example, aws:us-east-1 or gcp:europe-west1). Smart Tiered Cache takes over from there. Note that, on the dashboard, region hints can only be set for origins whose IPs we’ve detected as anycast.


On the Tiered Cache page, go to the Origin Configuration table and click the edit icon next to an origin IP to set its region hint.

You can set hints one IP at a time, or bulk-edit cloud regions for all your origin IPs at once. Beyond the dashboard, the same configuration is available via the API and through Terraform, so you can integrate it into your existing infrastructure-as-code workflows.


We’re launching with AWS, GCP, Azure, and Oracle Cloud, with more providers coming.

How Smart Tiered Cache for Public Cloud Regions works

Every few hours, we fetch the latest IP range files from each supported cloud provider. These files map every cloud region to its current set of IP prefixes, so when a provider adds, removes, or reassigns a subnet, we pick it up.


Smart Tiered Cache for Public Cloud system diagram

We match those subnets against our upper tier database, which is built from continuous latency probing refreshed every 15 minutes. For each cloud region, each matching subnet contributes a weighted vote based on its current upper-tier assignment. The upper tier with the strongest signal becomes the region’s primary upper tier. Primary and fallback always come from different points of presence (PoPs), so losing one PoP can’t take out both.

Some regions don’t have enough probe data, for example, perhaps the new region’s cloud provider is still rolling out, or the region has no origin onboarded to Cloudflare yet — so there’s nothing to vote on. We fall back to geography: the closest of our Tier 1 PoPs. As origins come online and probe data builds up, the region quietly switches from that geographic guess to the option backed by real data.

Try it now, and what’s next

All this means that the work of selecting the optimal region for your cache — the constant probing, the algorithmic choice of each region’s best upper tier, the geographic fallbacks, the failover across PoPs — runs on our side. Your job is selecting the region hint.

If your anycast origin sits on a public cloud, you can turn this on now. In the dashboard, go to Caching > Tiered Cache > Origin Configuration. Find your origin IP, click Set Region Hint, and pick your region.

Next up, we’re expanding to more providers, and continuing to teach Smart Tiered Cache to recognize more origin setups and pick the right path on its own. To learn more about how Tiered Cache can benefit your service, check out our Tiered Cache documentation.

Последният етаж на републиката

Post Syndicated from Емилия Милчева original https://www.toest.bg/posledniyat-etazh-na-republikata/

Последният етаж на републиката

През 2023 г. в Съединените щати спореха дали върховен съдия може да приема като подаръци частни полети и луксозни почивки от милиардер, без това да разруши общественото доверие в институцията. Три години по-късно България спори дали конституционна съдийка е летяла с политик, санкциониран за значима корупция. 

Двете истории изглеждат различни, но всъщност задават един и същи въпрос: какъв е етичният стандарт за хората, които стоят на върха на държавата? Също така показват, че независимостта на съда не започва с клетвата, а с механизмите за селекция и избор.

Евентуалните съвместни пътувания на конституционната съдийка Десислава Атанасова с олигарха Пеевски са поводът за такъв разговор, но не и неговата тема. Защото всеки конституционен съдия е нечий избор, а когато въпросният е предложен от парламентарната квота, неизбежно стигаме до политиците, които са го номинирали. 

Първият етичен кодекс на Върховния съд на САЩ

За назначения от президента Джордж Буш-старши съдия от Върховния съд на САЩ Кларънс Томас не е било проблем в продължение на 20 години да приема от милиардера Харлан Кроу, спонсор на Републиканската партия, луксозни пътувания с яхти и частни самолети и почивки, които обяснява като „лично гостоприемство“. Съдия Томас не е декларирал нищо от това в годишните си финансови отчети. Но има и още: Кроу закупил и реновирал дома на майката на Томас с цел да го превърне по-късно в музей на съдията. Оказва се, че е платил и за обучението в частно училище на правнука на Кларънс Томас. 

Скандалът със съдия Томас не стигна до обвинения в корупция, но принуди Върховният съд да приеме първия си етичен кодекс. Американска адвокатка коментира по този повод, че „когато начинът на живот на един съдия се субсидира от богатите и известните, това напълно подкопава общественото доверие“. 

Плаващите пясъци на институционалното недоверие

Когато говорим, че доверието в институциите ни е ерозирало, може би не си даваме напълно сметка, че тази ерозия все повече се превръща в окончателен разпад, при който от обществения договор остават само песъчинки, пълнещи плаващите пясъци, в които потъваме. От Валентин Вълканов.

Един съдия трябва да е винаги безупречен в своето извънсъдебно поведение и дейности – много повече от всеки политик. Политикът може да защитава определени интереси (на спонсори и бизнес лобита), да прави неморални компромиси, но това е недопустимо за съдиите, чиято единствена власт произтича от общественото доверие в тяхната независимост. 

„Пеевски–Атанасова“ не започва с полетите

Съвместните полети само извадиха под прожекторите съмненията, съпътствали избора на Атанасова още от самото начало. Критиките към издигането ѝ за конституционен съдия се дължаха на факта, че години наред тя беше една от най-разпознаваемите партийни фигури на ГЕРБ, с дълга кариера на депутат, но без професионален авторитет, който да балансира очевидната ѝ партийна биография. Ако не броим председателския пост на Правната комисия, който е институционален опит, Атанасова е била юрисконсулт в русенския психиатричен диспансер две години и още толкова – юрисконсулт на Многопрофилната болница за активно лечение в Русе.

Още при избора ѝ през януари 2024 г. критиците на кандидатурата ѝ предупредиха, че подобен ход размива границата между политиката и институцията, която трябва да стои над нея. Проблемът беше не само в биографията на Атанасова, но и в начина, по който я избра парламентът. 

Зад кандидатурата ѝ застанаха лидерите на тогавашната управляваща „сглобка“: Бойко Борисов (ГЕРБ), Делян Пеевски (ДПС), Кирил Петков, Христо Иванов и Атанас Атанасов (ПП–ДБ). Това беше политическа сделка заради промените в Конституцията, представена като институционален избор. Заедно с Атанасова в Конституционния съд (КС) влезе и Борислав Белазелков, номинация на ПП–ДБ. Още тогава за нито един от лидерите, поставили подписите си под кандидатурата на Атанасова, не са били тайна връзките ѝ с Пеевски. Като председателка на ПГ на ГЕРБ тя единствена заговори за квотен принцип при разпределението на местата в регулаторите, тоест и за включване на ДПС.

Днешният скандал с предполагаемите полети разкрива последиците от този безпринципен компромис. 

Начинът, по който една държава избира своите конституционни съдии, казва много повече за политическата ѝ култура, отколкото всички декларации за върховенство на правото. 

Десантът на партийните лейтенанти

На политическия епизод, който се задава на нашите екрани, много ще му отива „Клонираните атакуват“, защото явно ще получаваме още от същото. Емилия Милчева го нарича „десантът на партийните лейтенанти“. Да видим как ще се развие.

Кой определя нравствеността?

Последният етаж на властта, ако определим така КС, следва да се крепи на доверие. Авторитетът на избраните в него стъпва на професионализъм, независимост и безукорно поведение. Но от самото му създаване през 1991 г. политическата целесъобразност все по-често измества професионалните и етичните норми. 

Дебатът за етиката не е нов. Още през 1994 г., след назначаването на депутата от СДС Георги Марков за конституционен съдия, 54 народни представители поискаха КС да разтълкува какво означава конституционното изискване за „високи нравствени качества“, и оспориха президентския указ за назначението. Поводът тогава бяха твърдения за принадлежност на Марков към бившата Държавна сигурност. 

Конституционният съд отказа да разгледа въпроса по същество, като прие, че преценката дали кандидатът притежава необходимите нравствени качества принадлежи единствено на органа, който го избира или назначава. 

Така още преди повече от три десетилетия беше поставен въпросът кой всъщност носи отговорност да прецени какво означава „високи нравствени качества“. И тази отговорност падна върху органите, които номинират и назначават съдиите, независимо къде – Народно събрание, професионални гилдии, президент.

Изборът за конституционен съдия се превърна в награда за партийно служене, за минало на активен борец за демокрацията или за уреждане с пост заради обслужване на частни интереси на тесен кръг хора. Достатъчно е да се споменат имената на бившия депутат от ГЕРБ Анастас Анастасов и на бившия премиер от СДС Филип Димитров.

Но при Десислава Атанасова още при процедурата по избора ѝ се появиха критики за нейната непригодност – не само в професионален план. 

Понякога съмнението е достатъчно

В други европейски държави стандартът за конституционните съдии е различен. 

През 1997 г. френската полиция започва да разплита гигантската корупционна афера около държавната петролна компания Elf Aquitaine. Сред главните действащи лица се оказва Кристин Девие-Жонкур – любовница на председателя на Конституционния съвет Ролан Дюма, наричана от медиите maîtresse de la République („любовницата на републиката“). Разследването установява, че тя е получила милиони франкове, бижута, апартамент и други облаги срещу посредничество при международни сделки с оръжие и петрол. Сред подаръците е и чифт обувки за над 100 000 франка (около 25 000 евро при днешната покупателна стойност), платени с парите на Elf

Грешният въпрос за олигарсите

Ловът на олигарси може и да звучи като реформа, но не е. Докато се води битка дали този, или онзи е олигарх, моделът остава непокътнат и винаги намира следващите си герои. Реалността показва, че олигархията се побеждава с работещи институции. От Емилия Милчева.

Срещу Дюма, верен приятел на президента социалист Франсоа Митеран, течеше наказателно производство, но до окончателна присъда не се стигна. След като името му се появява в разследването, той подава оставка през 1999 г. Не защото съдът го е признал за виновен, а защото приема, че председателят на институцията, която тълкува Конституцията, не може да остане на поста, когато обществото се съмнява в неговата почтеност. 

По-късно той беше оправдан по най-тежките обвинения. Но принципът е непоклатим: 

конституционният съдия носи отговорност за общественото доверие в институцията, която представлява. 

Полският модел

Френският случай показва как една институция защитава авторитета си. Полският е доказателство какво се случва, когато я овладее политическа сила. 

Полша се превърна в най-яркия пример за политизиране на конституционното правосъдие. След като управляващата в периода 2015–2023 г. националистическа партия „Право и справедливост“ промени правилата за избора на конституционните съдии и назначи свои кандидати, Конституционният трибунал постепенно изгуби общественото доверие. Критиките към него бяха, че обслужва политическата власт, вместо да я ограничава. 

Една от големите промени, които извърши, беше, че полската Конституция има предимство пред правото на ЕС, което подкопава един от основните принципи на Общността. 

Европейската комисия започна наказателни процедури срещу Полша, а Съдът на Европейския съюз постанови серия от решения срещу полските съдебни реформи. 

След смяната на властта новото правителство на Доналд Туск обеща да възстанови независимостта на Трибунала, но правният регрес не се поправя лесно. Европейската комисия отчете, че Полша е представила план за възстановяване на върховенството на правото през 2024 г., но мерките бяха блокирани. Кабинетът на Туск се сблъска с институционален капан – президентско вето и блокирани закони.

Полският случай показва, че независимостта на конституционния съд не се разрушава с един скандал, а с поредица назначения, при които политическата принадлежност тежи повече от професионалния авторитет. Полша е и пример как чрез спорни назначения, отказ да бъдат признати вече избрани съдии, законодателни промени и овладяване на ръководството на Конституционния трибунал една политическа сила може да превземе последния етаж на властта. 

Sic transit gloria Boyki*

Емилия Милчева разнищва брауновото движение вследствие на създалото се в триъгълника на властта напрежение – и най-вече хаотичните танцови стъпки на Борисов, който непрестанно настъпва опърпания шлейф на партията си и се препъва в него.

Промяна на баланса

Скандалът около Десислава Атанасова и нейните евентуални опасни връзки със санкционирания за корупция олигарх и партиен лидер Делян Пеевски не е просто епизод от политическото всекидневие. Той поставя под съмнение етичния стандарт, по който България избира хората, призвани да бъдат последната инстанция по Конституцията. Ако за конституционния съдия е достатъчно да не е осъждан, но не и да бъде извън всяко основателно съмнение за каквото и да е нарушение, самата институция съвсем заприличва на зависимите от партиите „независими“ регулатори. 

Балансът в 12-членния български КС, където президентът, парламентът и общото събрание на съдиите от върховните съдилища имат право на равни квоти, също може да бъде променен. 

КС е институцията, която може да спре закон на парламента, указ на президента или да реши спор между най-висшите държавни органи. Именно затова всяко място в неговия състав е от особено значение. За да бъде прието едно решение, са необходими 7 гласа „за“, а при равен брой гласове оспорваната норма остава в сила.

Ако Десислава Атанасова подаде оставка, парламентът трябва да попълни овакантеното място, тъй като тя е излъчена от неговата квота. При доминиращо парламентарно мнозинство на „Прогресивна България“ именно тази политическа сила вероятно ще предложи следващия конституционен съдия. Като президент Румен Радев вече назначи четирима членове на КС: Сашо Пенов, Невин Фети, Янаки Стоилов и Атанас Семов. Още едно назначение, макар и формално от парламентарната квота, би променило чувствително баланса. 

КС не може да бъде по-независим от хората, които го съставят. Затова и скандалът около Десислава Атанасова не е личностен. Той е за това дали последният етаж на държавата ще остане над политиката, или постепенно ще се слее с нея. 

По буквите: Иванова, Донева, Христов

Post Syndicated from Зорница Христова original https://www.toest.bg/po-bukvite-ivanova-doneva-hristov/

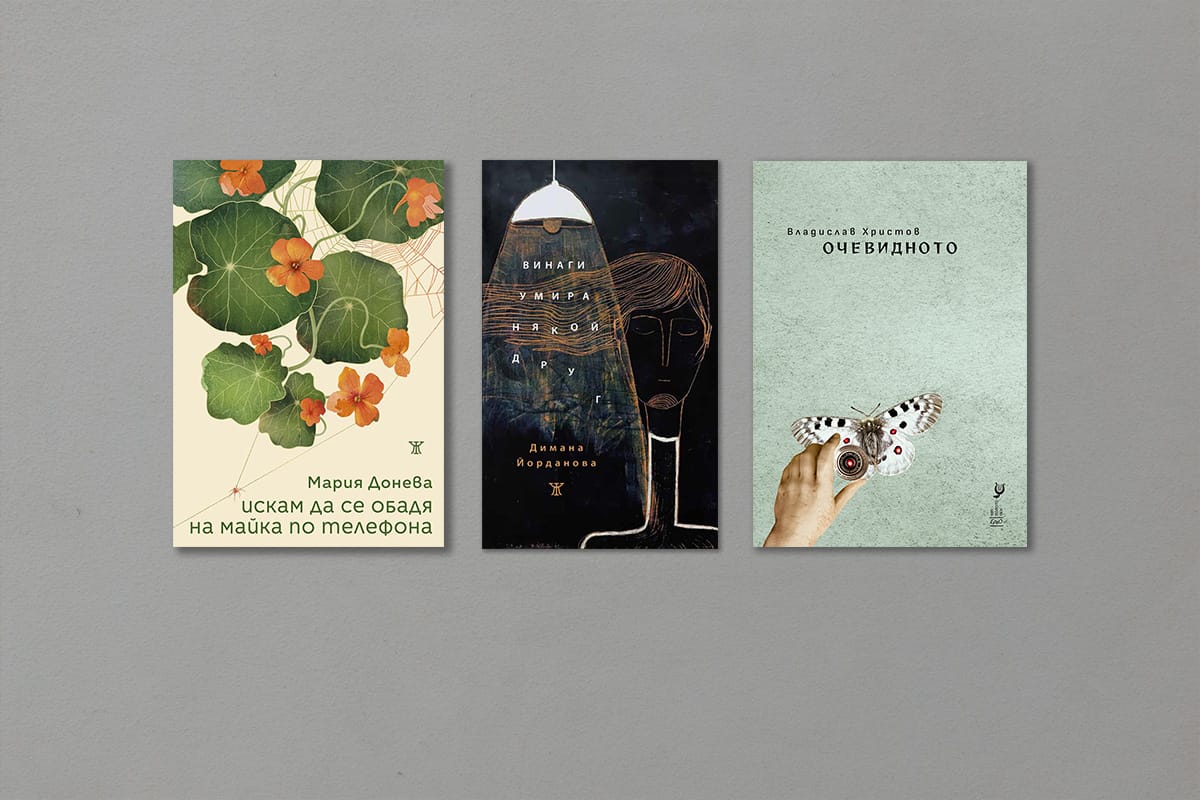
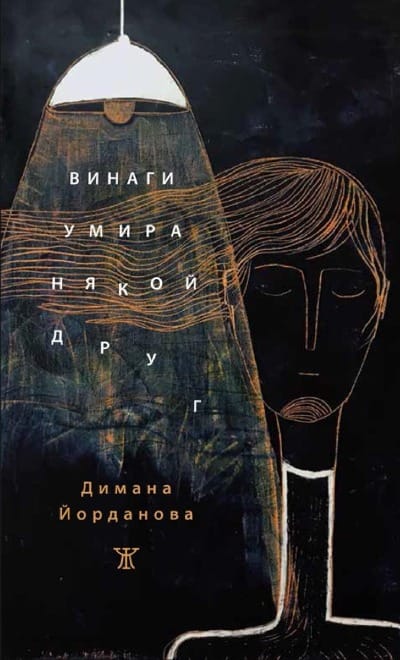
„Винаги умира някой друг“ от Димана Йорданова

По буквите: Иванова, Донева, Христов

Пловдив: изд. „Жанет 45“, 2026

Какъв е смисълът да се говори ясно за болестта и загубата? Как е разрешено да се говори за тях? Какъв е санитарният минимум на алегорията, зад който да се скриеш? Каква е функцията ѝ – да превръща казаното в поезия или да осигурява нужната двусмисленост, така че никой да не е длъжен да те разбира буквално?

Цензура ли е да престанат да те слушат?

Гневът в едно от стихотворенията на Димана Йорданова се излива тайно, като сивата вода от пране. Смъртта също е учтиво разположена от другата страна на вратата:

Благодаря, че ще почакаш да затворя вратата
и чак тогава ще се разпаднеш,
колко учтиво от твоя страна, мило момиче,
че не издъхваш в ръцете ми.

Димана говори на онзи, който не иска да слуша. Говори гневно, ту прозирно, ту в алегории, които нямат „приемлива“ страна: и буквалното, и преносното са еднакво неудобни. Алегориите на тялото са свързани с публичното пространство: не можеш да избягаш от разпада на едното в разпада на другото.

Давам под наем пространството, което тялото ми заемаше, 
на тихо и комуникативно място е, 
в близост преминава влак, 
по разписание закъснява, 
по презумпция дерайлира. 

До моя роден дом са отворили музей на илюзиите, пишеше Марин Бодаков в едно от последните си стихотворения. И също говореше за тялото като за нещо отделно, като за някого, с когото общуваш невинаги в разбирателство („от тебе искам прошка, скъпо тяло…“)

По буквите: Иванова, Донева, Христов

Гласът у Димана Йорданова вика тялото, което закъснява да се върне от игра, а то „прикляка в храстите, дриблира с топка от кожа, потно, побесняло за още, ниско като глава на кокиче“. Или се свива на стола под неговата тежест, опитва се да преговаря, да му обещава, да го придумва. Не съвпада с тялото си, но и не съвпада със себе си – в едно стихотворение единственото общо с вчерашното аз е вдлъбнатината в леглото, която постепенно трябва да бъде запълнена. В друго стихотворение дебелият гражданин, чийто критичен поглед виси над героинята като гащи на луната, я погребва всеки ден и тя всеки път отива на опелото – гледа отстрани и гледа погребана жената, за която никой не знае каква ѝ е била. Винаги умира някой друг – защото не искаме да слушаме за чуждото умиране, но и защото и ние не съвпадаме с нашето умиращо аз.

И слава богу! Тази книга е пълна с бяс, с гняв. Нейният език не е езикът „на забулената луна“, в нея няма неясни очертания, които читателят да запълни сам. Образите може да са ненадейни („заспали сме невинни, чисти, напикани, розови парченца от туловището на света“), но не и двусмислени. Неяснотата е вид колебливост, а тази книга е изпълнена с решимост. 

С решимост да излееш сивата сапунена течност на гнева пред всички, да придружиш тялото във всичките му превъплъщения до Бог, който ще го попита: „Какво направи с моя гняв?“

Дори само това стихотворение да съдържаше книгата, пак бих я препрочитала и подарявала. Или бих преписала някому изречението „всеки ден се сбивам за жената, която бях“.

Току-виж подсказала на някого, че има право да се бори за себе си.

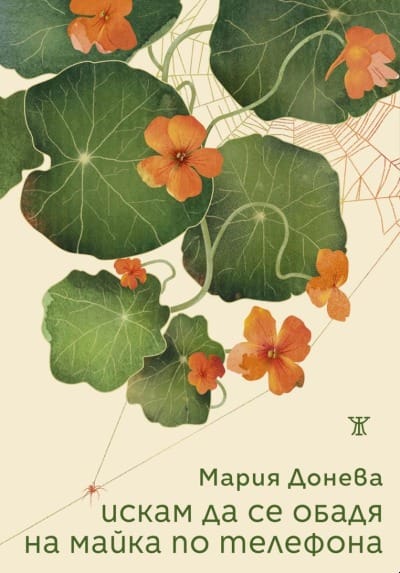
„Искам да се обадя на майка по телефона“ от Мария Донева

Пловдив: изд. „Жанет 45“, 2026

Тази книга щеше да бъде важна с всяко име на корицата, но е особено значима, защото е книга на Мария Донева. Защото нейният умел слог, топлота и внимателно отношение към читателя са създали широк кръг от хора, които ѝ се доверяват; кръг доста по-голям от обичайния литературен балон. Това доверие е изключително рядко сега, когато приятели и роднини лесно губят общ език. Мария Донева успява да създаде пространство, в което може да разговаря с всеки.

И сега е встъпила в това пространство, за да говори за траура, за скръбта по отишлия си родител. И за предварителния траур по другия, който гасне. За мъката по загубата – физическата и тази, която е по-трудно да предадеш в разговор: мъчно ти е за човека, който не е какъвто е бил. И за този, който самият ти си бил.

Опитайте да говорите с някого за това. Особено пък в неговите конкретни детайли. Опитайте да говорите за депресията, за загубата на смисъл, опитайте да кажете, че изнемогвате. Или че нямате желание да правите любимите си доскоро неща.

По буквите: Иванова, Донева, Христов

Казват, че грижата за тежко болен е огромна психическа и физическа тежест, която често води до депресия и други подобни състояния; че тя е диспропорционално поета от жените; и че е почти несподелима (никой не иска да слуша).

В тази книга тези теми са споделими.

Един смачкан човек
предпазливо се вдига, 
не да прави геройства – 
взима някаква книга.

Очилата къде са?
И жена му къде е?
За кого да се сресва?
И защо да живее…

В книгата има и воля за ведрина, и топлина (като в стихотворението, в което бащата се затичва, кретайки, да каже колко обича дъщеря си), във връщането на майката – в сънища, в които „ходи и се смее“, в самото усещане за липса, която си има име. И значи е тук. Но и в дословната честност, в която непознати един за друг читатели ще могат да тъгуват заедно, да се спасят заедно от повелята нещо да „преодолеят“, за да не пречат с тъгата си. Да могат да ѝ обърнат внимание, да се вслушат в нюансите ѝ – в загубата на смисъл, в онова, което не искаш да знаеш за себе си, в необяснимо гузното чувство, в страха, в трудно назовимите ѝ отсенки. И малко по малко, достигайки края на книгата, да видят как Мария Донева избира да завърши с обич. Да ѝ се доверят.

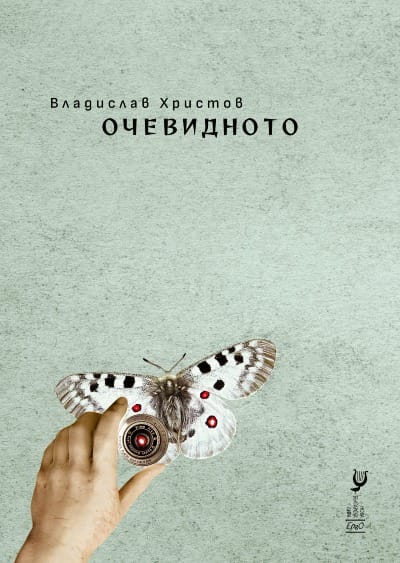
„Очевидното“ от Владислав Христов

София: изд. „Ерго“, 2026

За първи път от 2022 г. насам виждам българска книга, която да говори за войната. И то да говори не репортажно, не като журналистика; да говори като подземен тътен, като ромол на подземна река, като подкожна тревога, като птици, които летят ниско в приближаващата буря.

Да говори за природа и да говори за всичко останало, без да изпада в алегоричност: да помамва ума да си представи класическото романтично бягство на самотния естествоизпитател. Дори не естествоизпитател – човек с фотоапарат, свидетел.

И да го остави да види в самата природа онова, от което е бягал: насилието, подземните нива на страха, кръвта, собствената си гузност.

По буквите: Иванова, Донева, Христов

Тази поезия прилича на Фрост по това, че е пълна с катерици, къпини, малинов сок, кукуряк, диви прасета, клек, цъфнал орлов нокът, пчели, кълвачи, секачи, хвойна, божи кравички, врабчета, хралупи, всякакви имена на живота, като заклинания против мрака, който тегне из нея. Мрак, който също е част от природата.

И се различава по усещането за явна заплаха: войниците, които те обграждат, докато снимаш божи кравички, спусъка, наслоените сажди в „чушкопека на войната“, кръговрата на насилието, от което човекът е само част – непълен кръговрат, без усещане за справедливост, като в „гигантската секвоя наби баобаба, баобабът наби кедъра…“ или като в стихотворението, в което пчелите, забравили за всичко, се роят, мечката, забравила за всичко, гледа кошера, а ловецът, гледащ мечката, решава да отложи спусъка… само за този път. 

Перспективата се сменя; фотоапаратът става окуляр, фотографът – ловец. В книгата тлее усещане за скритото у самия теб насилие, съмнение в смисъла на човешкото – като в прегризаната по средата жаба, която не прави разлика между теб и пора, като в децата, израснали в окопите, които не са виждали куче, но отлично лаят и хапят.

Антиутопична книга, в която природата е едновременно спасителна и зверска, жестока. От време на време из страниците срещаме думата „ние“, чийто смисъл мигрира: няколко ученици на дзен учител; неизвестно множество, което наблюдава животните и се учи от тях (наблюдава и хората, но от тях нищо не научава); застава спрямо животните от другата страна на барикада, воюват; стоят в окопи, в бомбоубежища, оплакват се от квакането на жабите в окопите, но не и от нуждата да стоят в тях. 

Антиутопична книга, в която най-страшна е собствената ти природа. Безмилостна и милостива, защото те изправя пред това, заради което се страхуваш да прочетеш новините – страха от войната, екологичния страх, подземния тътен на тревогата. Очевидното.


В емблематичната си колонка „Ходене по буквите“, започната още през 2008 г. във в-к „Култура“, Марин Бодаков ни представяше нови литературни заглавия и питаше с какво точно тези книги ни променят. В началото на 2020 г. той я пренесе в „Тоест“. Вярваме, че е важно тази рубрика да продължи. От човек до човек, с нова книга в ръка. От края на 2021 г. по буквите тръгна Зорница Христова.

Активните дарители на „Тоест“ получават 20% отстъпка от коричната цена на всички книги на над 15 български издателства. Кои са те – вижте в условията на Читателски клуб „Тоест“.

AI Surveillance and Social Progress

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/ai-surveillance-and-social-progress.html

In the near future, AI-powered surveillance systems will be able to track everything we do in public, and much of what we do in private. And if we do something wrong—shoplift, litter, jaywalk, you name it—the system will notice, retain it, tie it to your official government record, communicate that fact to you, and provide real-time alerts to any relevant authorities… and maybe also to the general public.

Think of these systems as automated speed cameras, but on steroids. Only they’ll enforce not just speed limits, but any other rule you can imagine. And you won’t receive a ticket weeks later by mail; you’ll be informed about and fined for your violation immediately.

These systems will combine powerful AI, public and private surveillance via real-time facial recognition technology and digital tracking, mass databases and highly personalized enforcement. If deployed at scale, they will have profound chilling effects not just on personal freedoms, but democracy and social progress itself.

China has been developing its surveillance infrastructure for years. The country has over 600 million surveillance cameras, increasingly powered by AI and facial recognition to enforce legal and social rules. Take the case of Lao Duan, a Chinese citizen blacklisted by the system after he lost his job and was unable to repay a series of loans. When he visited Beijing, the city’s AI surveillance system identified him by his face at a major intersection and displayed his face, name and citizen ID number on a large electronic billboard nearby with a message that he was an untrustworthy person. Similar systems are now being deployed across China and integrated with its infamous online monitoring, censorship and social credit systems.

AI surveillance is now being experimented with in North America, South America, Europe, Asia and Africa. According to a new report, the US Department of Homeland Security is rapidly increasing its use of AI-based surveillance, including facial recognition and the monitoring of social media accounts, to keep tabs on immigrants, dissidents, journalists, legal observers and protesters. While the systems are ostensibly used to maintain security and public safety, the real aim is often social control. Larry Ellison, CEO of Oracle—a powerful tech giant that works closely with the Trump administration—has said: “Citizens will be on their best behavior because we’re constantly recording and reporting.” The chilling effects are the point.

AI surveillance raises a range of public policy challenges: technical biases, unauditable systems, and inflexible automated law and social rule enforcement that can promote discrimination and undermine transparency, accountability and the rule of law. But we believe the most urgent and long-term impact will be its broader chilling effects.

In a new book, Chilling Effects: Repression, Conformity, and Power in the Digital Age, Jon Penney explains how surveillance, technology and power can be weaponized to influence behavior at scale. Surveillance, personalization, uncertainty and authority are all key mechanisms to increase the scale and impact of chilling effects. They cause people to self-censor their words and actions, to become more conformist and compliant and thus easier to manage and control. And the effects are additive: the more mechanisms employed, and the more powerful the form, the greater the chill.

Computerization has long allowed data collectors to track our locations, collect lists of whom we communicate with, and monitor our spending habits—unless we use cash. What’s new is an unprecedented fusion of each of these mechanisms, persistent and unrelenting. AI brings an analytical ability to spy on the contents of our communications, and to answer sophisticated questions about our whereabouts and activities: actions that previously required human analysts are now automated. The result will be a kind of supercharged societal level of chilling effects where fear, self-censorship and groupthink reign, and dissent, creativity and innovation become increasingly rare.

In this atmosphere of fear and conformity, risky ideas, social activism and self-reinvention—especially by disfavored groups and targeted populations—are also chilled. This will have long-term effects on social progress.

Consider the relatively recent societal normalization of same-sex relationships and the recreational use of marijuana. Over the decades, those ideas slowly progressed from being both immoral and illegal, to moral but still illegal, and finally to both moral and legal. But in order for any of that to happen, there had to be a counterculture that was able to experiment and eventually demonstrate to the world that morality could change over time. To the extent that AI surveillance chills this sort of experimentation in public or in private, social progress becomes impossible.

There are no real historical precursors to this; these technologies are too new. Even the most notorious and large-scale domestic surveillance program in US history, the FBI’s use of wiretapping, physical mail opening, informants and paper index cards to track alleged communists during the 1950s and 1960s, appears genuinely archaic in light of modern AI-enhanced surveillance. So does East Germany’s human-centric surveillance network during the cold war. Only science fiction, from the likes of George Orwell or Aldous Huxley, comes close. But even Big Brother’s “telescreen” feels decidedly mid-20th-century by comparison.

But we need not sit idly. Now that we recognize the danger of AI-enhanced mass surveillance, we can make the policy choices not to implement it. Bans on facial recognition and other forms of identification tech can slow development; robust new privacy and data protections can restrict data tracking and retention; AI regulations can curtail its most invasive uses; and structural reforms can help us scrutinize and break up powerful state/tech cartels that pave the way for technological excesses like AI surveillance.

The chill of AI-powered mass surveillance will suffocate the very foundations of healthy democratic societies. But we can still choose a different path.

This essay was written with Jon Penney, and originally appeared in The Guardian.

Enhancing your enrichment offer? Code Club is the answer

Post Syndicated from John McAtominey original https://www.raspberrypi.org/blog/code-club-enrichment-offer-schools-free-support/

There’s something really special about a Code Club. It’s a unique space for young people to get creative with technology on their terms, explore what interests them, and learn through experimenting and having fun. But speak to any Code Club leader and they’ll tell you: Code Club delivers so much more than just coding skills.

Two young people work together at a Code Club.

In the thousands of free Code Clubs across the world, you’ll see young people not only make amazing tech creations, but also grow as people. You’ll see young people find their voice and grow in confidence as they present what they’ve made to a room full of friends and parents. You’ll see them show a problem in their code to their friends and work as a team to fix it. You’ll see young people come up with the most creative digital solutions to challenges they see around them.

The ideal enrichment activity for the age of AI

We’re delighted that the UK government recently recognised Code Club as a key resource to help schools enhance their enrichment offer. This confirms what the community tells us, and what independent research shows: that Code Club works. Not only does it help young people develop their programming skills, but it also builds life skills including confidence, resilience, and problem solving. And Code Club is completely free. Schools, libraries, and community centres can set up Code Clubs using their existing equipment, and register their clubs to access all our free resources and support for getting started and running successful club sessions for the long term.

A Code Club session in a school classroom filled with young people working together at laptops.

And what about AI? There’s no getting around it, at the moment AI dominates almost every conversation about computing education, and this includes enrichment and non-formal activities too. All young people should have the power and agency to understand, question, and shape the AI systems increasingly affecting their lives. We believe that kids still need to learn to code in the age of AI, and we’ve created resources and coding projects for Code Clubs that help young people understand how AI tools work, and how to use them carefully. 

A Code Club in every UK school and library

Last year we announced our ambition to support every school and library in the UK to set up a free Code Club so that young people can develop the skills and knowledge they need to thrive in the age of AI.

Two young people smiling whilst working on their laptop with an adult mentor by their side.

Now we’re pleased to announce a package of free support for UK trusts and local authorities that are interested in becoming growth partners and setting up Code Clubs across their networks. If you join us as a growth partner, you will get:

  • Direct support from a member of our team, who will work with you to get new Code Clubs running
  • Training for your team on how to run a great Code Club experience
  • Exclusive partner logos to use on your website and in social media posts
  • Resources to promote and celebrate your clubs
  • The chance to be included in our global communications
  • Priority places at our community events
  • Access to a digital platform to monitor and manage your clubs
  • A welcome pack including some of our most popular resources
  • And of course, easy-to-follow projects for your young people

If you would like to find out more about how Code Club can enhance your enrichment offer, how easy it is to get started, and how we can help, please get in touch!

The post Enhancing your enrichment offer? Code Club is the answer appeared first on Raspberry Pi Foundation.
Не, националният ни интерес не сочи към Москва

Post Syndicated from original https://www.toest.bg/ne-natsionalniyat-ni-interes-ne-sochi-kum-moskva/

Не, националният ни интерес не сочи към Москва

Според премиера Румен Радев България не бива да подкрепя поредния пакет европейски санкции срещу Русия, защото това щяло да навреди на националния ни интерес. Подобно твърдение е толкова абсурдно, че човек си задава въпроса чий национален интерес има предвид премиерът – българския или руския. И дали слага знак за равенство между двата? 

Тук следва да преговорим някои факти от най-новата история на страната ни, които сами отговарят на друг въпрос: 

извършва ли Румен Радев държавна измяна, работейки за интересите на най-опасния враг на България? 

Преди да преминем обаче към същината на темата, нека повторим и няколко факта за продължаващата вече пета година руска агресия срещу Украйна:

Кой е българският национален интерес?

Причините страната ни да не желае Северна Македония да стане част от ЕС са многообразни, а акцентите в тях – променливи. Светла Енчева минава през някои от популярните „опорни точки“…

Законът, глупако

С пълномащабната си и непредизвикана агресия срещу Украйна Русия на Путин нарушава общочовешките ценности мир, хуманизъм и справедливост (така са дефинирани и в Конституцията на Република България). Този факт признава дори самият Румен Радев след началото на войната. Законите на страната пределно ясно чертаят къде стои българският национален интерес. Преамбюлът и член 24 от Конституцията на България ни определят като правова нация, чиято външна политика се гради върху принципите на международното право и зачитането на суверенитета. Кремълската агресия срещу Украйна е явно отрицание на всеки от тези конституционни принципи. 

Нещо повече, в действащата Актуализирана стратегия за национална сигурност на Република България изрично се дефинира националният интерес през пълноценната ни интеграция в Европейския съюз и НАТО, както и чрез постигането на пълна енергийна и икономическа независимост от монополни външни фактори. Всяко действие на Москва от 2014 г. насам – от незаконната анексия на Крим, през спирането на газовите доставки, до хибридните атаки и дезинформационните кампании срещу цяла Европа – е насочено директно срещу стратегическите стълбове на българската държава. 

В този контекст всякакви опити на Румен Радев да оправдае руските интереси и да блокира съюзническата помощ под предлог, че брани „националния интерес“, са в крещящо противоречие с фундаментите на българската държавност. Да работиш за умишленото изолиране на България от нейните съюзници в ЕС и НАТО в полза на агресора не е прагматизъм, а съзнателно прокарване на вражеска политика, която цели да превърне страната ни в уязвима и безгласна територия, неспособна да защитава собствения си интерес.

Как Радев постави България на картата

В края на първата година от започването на войната в Украйна вече е ясно кой от коя страна на историята стои. Това не важи за България, защото тук все още не можем да преглътнем факта, че „национален“ е различно от „руски“ интерес. Как президентът участва във всичко това – анализ на Емилия Милчева.

Когато Радев каже „прагматизъм“, разбирайте „слугинаж на Москва“

Българската външна политика от края на комунизма насам е зациклила в лутане, белязано от тежки стратегически грешки. Процесът започва в средата на 90-те години, по време на управлението на БСП – пагубен опит на тогавашното социалистическо правителство начело с Жан Виденов да лавира между Запада и Изтока, което вместо дивиденти донесе на страната пълна международна изолация и икономически колапс. Този урок бе временно научен в края на десетилетието, когато България категорично заяви цивилизационния си избор, довел до историческото приемане в НАТО през 2004 г. и в Европейския съюз през 2007 г. Въпреки това завоюваната позиция бързо бе размита от десетилетия на половинчата интеграция, недовършени реформи, икономическо снишаване пред руските енергийни монополи и военно снишаване пред Путин.

Проблемът ескалира след незаконната анексия на Крим през 2014 г. и последвалата пълномащабна руска агресия срещу Украйна. Вместо да затвърди позицията си на лоялен съюзник на предната линия на свободния свят в новите реалности на радикално пренареждащ се световен ред, България отново започна да работи срещу собствения си национален интерес. Тази динамика беше циментирана по време на управлението на ГЕРБ, когато лично премиерът Борисов блокира инициатива на НАТО за обща мисия в Черно море. Чрез светкавичното построяване на газопровода „Турски поток“, завършен през 2019 г., България пък практически помогна на Путин да заобиколи енергийно Украйна и да премахне последните пречки преди нападението срещу Киев през февруари 2022 г. 

Именно това дългогодишно саботиране на националния интерес от страна на ГЕРБ, маскирано като „балансиране“, създаде перфектната почва за днешната радикална проруска линия на Румен Радев, чрез която България открито капитулира пред Кремъл и се превръща де факто в руски васал. След 2019 г. като президент Румен Радев състави няколко служебни кабинета, които възродиха същата онази призрачна реторика на „неутралитет“ и „прагматизъм“, започната от Виденов и наложена от Борисов. България в лицето на Румен Радев се координираше с режима на Виктор Орбан, най-близкия до Москва европейски политик. 

Радев и Орбан на практика действаха в синхрон като проводници на руските интереси в рамките на ЕС и НАТО чрез системно бламиране на общите европейски санкции, блокиране на военната помощ за Киев и легитимиране на реториката на Путин под паравана на „защита на националния суверенитет“. Тази политика позиционира България като несигурен, двуличен и пробит партньор в ЕС и НАТО. Така три десетилетия след края на комунизма, вместо България да действа като независима страна в международните процеси, правителството на Радев я превръща в „троянски кон“ и поема щафетата от вече бившия унгарски премиер, за да продължи разбиването на европейското единство пред лицето на руската агресия.

Българо-унгарската ос: Съюзниците на Путин в ЕС и НАТО

Радев в България и Орбан в Унгария си подават топката по демаркационната линия между ЕС и Русия. Твърде често тази топка минава в полето на Русия, където удобно я отиграва Путин. Този мач сме го гледали. Въпросът е има ли съдия и къде са му червените картони.

Сред разгарящи се световни конфликти България на Радев ще бъде лесна жертва

2025-та беше годината с най-много активни военни конфликти от Втората световна война насам. Заради фактори като политическа нестабилност, икономически кризи и климатични промени тази опасна динамика ще продължава и ще се разраства. И докато най-развитите държави в света, притежаващи най-модерни армии, се надпреварват за сътрудничество с Украйна, кабинетът на Радев тласка България в обратната посока. САЩ, Канада, Великобритания, Германия, Франция, скандинавските и балтийските държави, страни от Близкия изток и Япония са сред тези, които активно си взаимодействат с Украйна в сферата на сигурността. По този начин те максимално бързо усвояват съвременния украински боен опит и внедряват най-високи технологии, като дронове и изкуствен интелект, за укрепване на собствената си сигурност.

България също сключи споразумение с Киев в началото на 2026 г. То беше остро разкритикувано от Радев, който малко преди това беше подал оставка като президент. Аргументите му тогава бяха достойни за роман на Джордж Оруел. Според Радев действията за модернизация на българската армия по най-високи стандарти представляват „дългосрочни ангажименти, които покачват рисковете за националната сигурност“. Такава логика би била вярна, ако Радев има предвид сигурността на режима на Путин, а не тази на България.

Как Русия унищожава българската идентичност в окупираните територии на Украйна

В България почти не се говори за десетките хиляди българи под руска окупация в Южна Украйна. Междувременно обаче се затварят училища, изчезват културни центрове, а една вековна общност живее под натиск и в несигурност. От Александър Малинов.

Пред страната ни в момента има два пътя: или да защитава националния си интерес, като последва примера на изброените по-горе страни, и да разчита на сътрудничество с Киев за модернизиране на отбранителните си способности; или по заповед на Москва да бъде просто територия без собствена защита, превръщайки се по този начин в лесна жертва за всяка задаваща се хибридна или конвенционална агресия. 

Като блокира обмена на технологии и съвместните учения с Украйна, Румен Радев обрича българската армия на пълно и фатално технологично и тактическо изоставане. 

Този процес вече тече, а само след няколко години пропастта между съвременните военни доктрини и нашите остарели, наследени от комунизма концепции ще стане непреодолима.

Къде е опозицията?

Обречена ли е обаче България със зависими от Русия политици начело? Не, все още не. Но докато путинистите на власт теглят страната към Москва, т.нар. проевропейски партии дължат на обществото и на избирателите си поне някакво противодействие срещу предателската политика на кабинета „Радев“. Дотук не сме видели такова. Все пак „Демократична България“ и „Продължаваме промяната“ са идейни наследници на онези политически сили, които поведоха борбата срещу зависимостта на България от Москва през 1990 г., спасиха страната от икономическа катастрофа през 1997 г. и направиха нужните реформи, за да бъдем днес част от ЕС и НАТО. 

Защо, след като поведоха най-големите протести в България през XXI век, лидерите на проевропейските партии мълчат точно сега, когато опасностите пред България са огромни и страната има най-голяма нужда от тяхната активност? Има ли кой да отговори на този въпрос навреме, или ще трябва да си го задаваме един на друг, докато не стане прекалено късно?

I like using scrollbars

Post Syndicated from arp242.net original https://www.arp242.net/scrollbar.html

I like to use scrollbars. I move my mouse cursor to the scrollbar handle and
move it about – scrolling like this is so much faster than with the wheel if you
want to scroll more than a few lines.

I didn’t notice how often I did this until sites started breaking this. It seems
to be fashionable to put a margin around the entire document, resulting in the
scrollbar no longer being aligned to the edge of the screen.

This is an absolute bollockache because now you can no longer just move the
mouse to the edge of the screen: you need to place it exactly on the
scrollbar, requiring far greater precision.

You can see an example at /scrollmargin.html. You need a
device with a mouse cursor to see the problem of course.

Some real examples, all of which started doing it in the last year or so:

  • FastMail
  • Outlook365
  • Stack Overflow “Beta Redesign”, although that was aborted.
  • Spotify (example)
  • GitLab (example)
  • Couchsurfing now completely hides the scrollbar (example)
    (aside: I am not saying that Couchsurfing has been infiltrated by AirBnB
    agents to run this communist woke libtard competition in to the ground, but I
    am saying that nothing Couchsurfing has done over the last 10 years
    contradicts that hypothesis.)

There is of course also the perennial “inappropriate scrollbar styling” problem,
and recently ultra low contrast have also gained popularity; for example:

I’m not against any scrollbar styling; in some cases it’s appropriate. Some
more playful websites, some very specific and rare webapp use cases, things like
that. I’m not a “system behaviour in every single last scenario” purist. The
MariaDB reference docs is very much not one of those cases.


I like using scrollbars. I can’t be the only person who does. You’re frustrating
users for no reason other than following some fad that makes things look ever so
marginally nicer. No one pays that much attention to your design and they won’t
notice. In ten years time everyone will look back at this in the same way we
look back that extremely low contrast text fad from a decade ago: “yeah, that
was rather silly”.

Scaling Grab’s Data Lake: Our journey to Apache Iceberg adoption

Post Syndicated from Grab Tech original https://engineering.grab.com/our-journey-to-apache-iceberg-adoption

Introduction: The evolution of Grab’s Data Lake

At Grab’s scale, managing petabytes of data across billions of S3 objects demands more than a storage layer. It demands a robust architectural primitive that supports the high-concurrency needs of a modern “Lakehouse.” Our goal is full storage-compute separation, leveraging S3 as an elastic foundation for both near-real-time metrics and large-scale batch transformations.

For years, the vast majority of our tables were Hive Parquet, managed through the Hive Metastore with a directory-based layout. This model served us well, but as data volume grew, the directory-and-metastore approach became the limiting factor. We are now transitioning to a table-centric architecture built on modern table formats, treating data as a first-class primitive to ensure consistency and performance across our internal data transformation platforms: Slide, which powers batch transformations, and Hugo, which handles online-to-data-lake ingestion. Along the way, we also built the UnifiedSparkCatalog, a unified Spark catalog that hides table-format differences from users entirely, which we are open-sourcing alongside this post.

The catalyst for change: Challenges with Hive Parquet

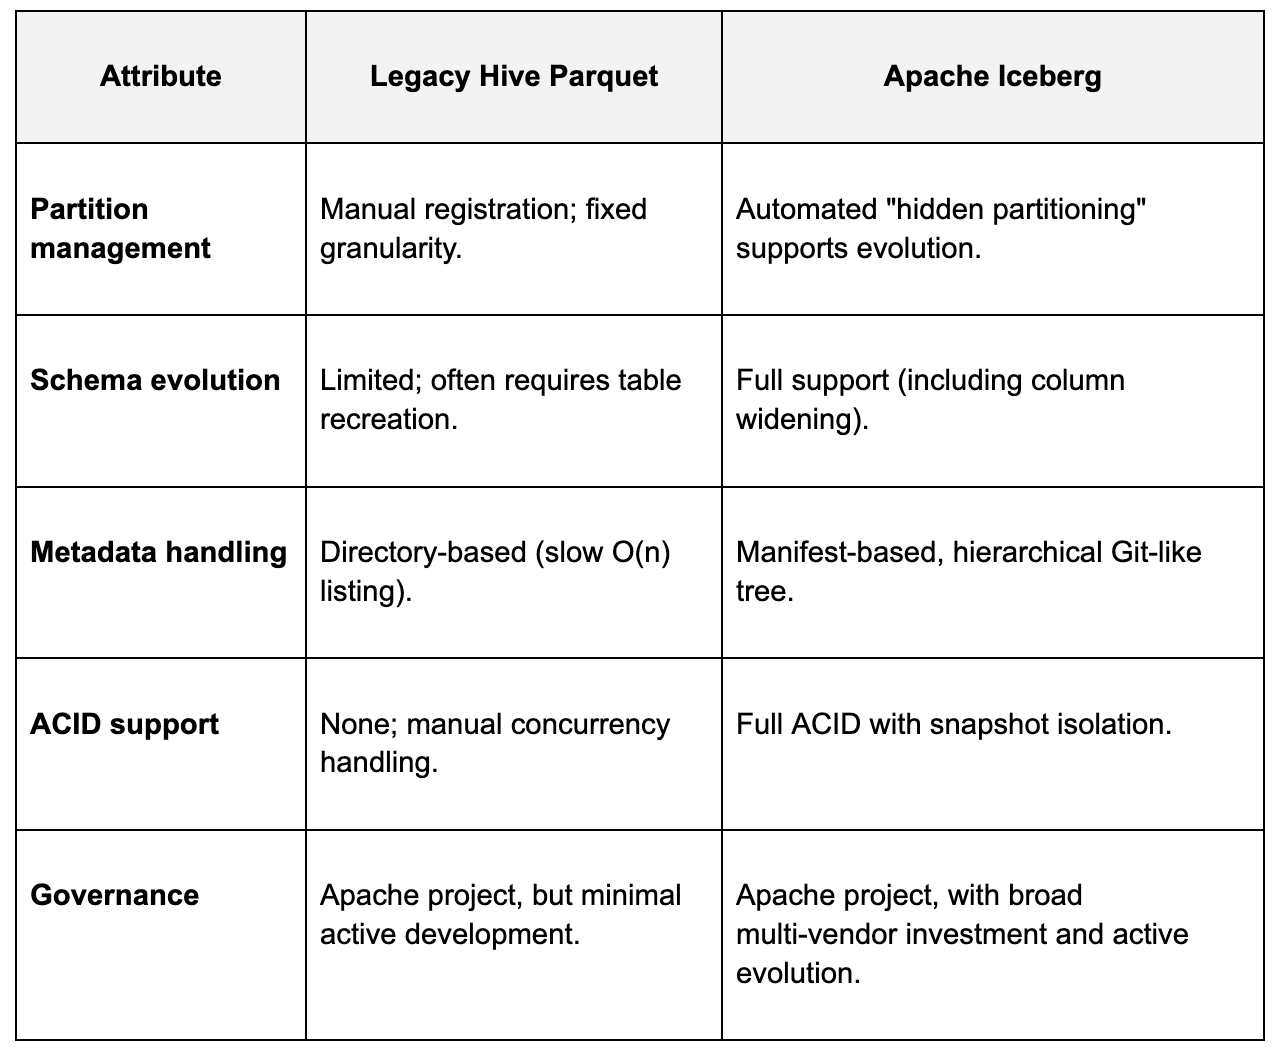
For years, Hive Parquet was the backbone of our Data Lake, representing the vast majority of our tables. However, as data volume scaled, the architectural limitations of directory-based storage became apparent. We identified four primary bottlenecks:

  • Catalog latency: The Hive Metastore (HMS) became a centralized failure point. High concurrency during metadata access led to O(n) listing overhead, where query planning time scaled linearly with partition count, crippling throughput.
  • The small file problem: The directory layout left us with severe file fragmentation. Certain Machine Learning (ML) datasets had an average file size under 1 MB, with thousands of files in each partition. At this scale, the overhead of S3 object listing and metadata request latency drove up Application Programming Interface (API) costs and slowed scan operations.
  • Operational toil: Data engineers faced constant manual overhead for partition registration. Without native ACID support (no native UPSERT or DELETE), teams relied on complex workarounds to manage data changes carefully.
  • The broken information loop: A fundamental disconnect existed between the catalog and storage. Because the HMS, not the storage layer, was treated as the source of truth, direct S3 modifications frequently left the catalog stale and out of sync with the actual state on disk.

Why Iceberg? Strategic alignment and future-proofing

We evaluated several open table formats before selecting Apache Iceberg as our default. The deciding factors came down to community governance, engine compatibility, and long-term flexibility.

Recent industry momentum, including growing cloud-native support for Iceberg, further validates this direction. We are positioning Grab to be format-agnostic in the long term, but Iceberg provides the most mature foundation today.

Comparison of Legacy Hive Parquet and Apache Iceberg

Adopting Iceberg at scale

Migrating an established lake is not a flag flip. Our challenge was rolling out Iceberg across a lake that was overwhelmingly Hive Parquet, queried by many engines and teams, without breaking the downstream consumers that depended on those tables. Rather than converting everything at once, we moved the highest-value tables first. The efficiency gains across our production workloads have been substantial. Here are representative examples:

  • Query performance via Z-ordering: On a high-traffic navigation dataset, we achieved roughly a 10x improvement in query runtime. Z-ordering co-locates rows with similar values across specified dimensions, enabling Trino to leverage data skipping and min/max statistics to prune irrelevant files during query planning. This reduced query runtime from 70 seconds to 6 seconds.
  • S3 API cost reduction: For a heavily queried operations table, daily S3 API costs were reduced by up to 95% with no changes to the queries themselves. Larger file sizes and the elimination of expensive object listing during query planning drove most of the savings.
  • Compute savings: For a dataset used in funnel analysis, we reduced cluster resource usage by approximately half. A separate ML feature pipeline also improved feature freshness for downstream models.

The UnifiedSparkCatalog: Making mixed formats transparent

Migrating to Iceberg solved our storage and metadata problems, but it surfaced a new one at the developer-experience layer. Modern table formats like Delta, Iceberg, and Hudi each implement their own custom catalog that extends Spark’s SessionCatalog. In a standard Spark runtime, only one catalog implementation can be set as the default spark_catalog. Supporting additional formats requires explicit catalog declarations, meaning users must reference tables with format-specific prefixes like iceberg_catalog.schema.table or delta_catalog.schema.table.

With Iceberg, Delta, Hudi, and Hive tables now coexisting and tables actively migrating between formats, this created two problems: engineers had to know the underlying format of every table they queried, and any format migration silently broke every downstream query that hardcoded a prefix.

The UnifiedSparkCatalog is our answer. It is a unified Spark catalog that abstracts the complexity of working with mixed table formats so users never need to think about which format a table uses. We took inspiration from Trino’s Table Redirection, a feature that transparently points a query at the right connector when a table’s format differs from the catalog it was queried through. Our Spark equivalent works as follows:

How it works

  1. Table detection: The catalog loads metadata from the Hive Metastore.
  2. Format identification: A TableTypeDetector utility identifies the format based on metadata properties (e.g., the provider field) or path-based inference.
  3. Operation routing: The catalog delegates the operation to the correct format-specific catalog (Iceberg’s SparkCatalog, Delta’s DeltaCatalog, etc.) without requiring any prefix from the user.

Key design decisions

  • Lazy initialization: Catalogs for each format are initialized only when first needed, reducing startup overhead. If a format’s JAR is missing from the classpath, initialization continues gracefully. The catalog simply skips that format rather than failing the entire session.
  • Naming as spark_catalog: The catalog reports its name as spark_catalog because Spark treats this name specially for legacy Hive Data Manipulation Language (DML) operations. Many internal Spark code paths check for this exact name to determine whether to use Hive-compatible logic for inserts, updates, and deletes. Using any other name would break legacy Hive table operations.
  • Catalog reuse: Before creating a new catalog instance, the system checks whether one already exists in Spark’s catalog manager. This preserves compatibility with plugins like OpenLineage, which inspect catalog class types for lineage extraction.
  • Fallback behavior: If a table is not found in the expected format-specific catalog, the system falls back to the base session catalog, ensuring robust behavior for standard Hive tables.

We are open-sourcing UnifiedSparkCatalog alongside this blog post. The code and documentation are available here.

Lessons learned and overcoming hurdles

Scaling Iceberg across a large ecosystem revealed several technical nuances:

  • Hive lock contention: We encountered “zombie locks” in the HMS that blocked commits. We traced this to a low read timeout on the metastore side under high load. Adjusting retry intervals and increasing the timeout resolved the issue.
  • Timestamp handling: Spark 3.4 introduced TIMESTAMP_NTZ (no time zone), while Iceberg defaults to TIMESTAMP_LTZ (local time zone). This caused compatibility issues with legacy Hive views. We resolved it through a custom migration workflow and targeted patches to our Trino deployment to ensure consistent casting.
  • Storage tier costs: Generating Iceberg metadata involves reading historical data, which can trigger a one-time cost spike as files move between S3 storage tiers. To manage this, we prioritize migrations based on a table’s scan frequency and API operation costs rather than migrating the entire lake at once.

Conclusion: The road ahead

Apache Iceberg is now foundational to Grab’s data strategy. It is the default format for Slide and Hugo, and adoption is expanding across our compute platforms.

Looking forward, we are experimenting with Storage Partitioned Joins to eliminate shuffle stages in Spark and monitoring the Apache XTable project to maintain interoperability between formats. Our journey does not end with adoption. We will continue contributing back to the ecosystem, starting with the upcoming release of the UnifiedSparkCatalog.

Acknowledgments: This journey was made possible by the dedicated efforts of the Data Engineering, Infrastructure, and Search & Personalization teams at Grab.

Join us

Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Introducing OAuth Support for AWS MCP Server

Post Syndicated from Vaibhav Chowla original https://aws.amazon.com/blogs/security/introducing-oauth-support-for-aws-mcp-server/

AWS MCP Server using the same credentials and sign-in methods that you already use for connecting to the AWS Management Console or AWS Command Line Interface (AWS CLI) through a familiar browser-based experience powered by industry-standard OAuth. This new sign-in path supports AWS Identity and Access Management (IAM) federation, AWS IAM Identity Center, and root or IAM users.

In addition, AWS is introducing several new security and governance tools, including: new global condition keys for OAuth, token introspection and revocation, dynamic client registration, new AWS CloudTrail elements, and a new API for headless OAuth connectivity. All of this is compatible with your existing IAM configuration including permissions, roles, and federated access.

In this post, you’ll learn how to connect your agents to the AWS MCP Server, understand how AWS Sign-In authorizes agent access, and manage access using new security and governance capabilities.

How to connect an agent to the AWS MCP Server

This walkthrough uses Claude Code, but the same steps apply to any agent that supports Model Context Protocol (MCP) such as Kiro, Codex, and Gemini. See Setting up the AWS MCP Server for how to connect the AWS MCP Server to an agent.

Prerequisite permissions

To connect an agent to the AWS MCP Server, you’ll need the IAM permissions required for OAuth-based sign-in. The following AWS CLI command adds a managed policy with required permissions to your IAM role (remember to replace <MyRole> with your IAM role):

aws iam attach-role-policy \
  --role-name <MyRole> \
  --policy-arn arn:aws:iam::aws:policy/AWSMCPSignInOAuthAccessPolicy

Step 1: Configure the AWS MCP Server on your agent

Run the following command to add the AWS MCP Server endpoint to your agent’s configuration as shown in Figure 1:

claude mcp add --transport http aws-mcp https://aws-mcp.us-east-1.api.aws/mcp

Figure 1: Adding the AWS MCP Server endpoint to Claude Code

Figure 1: Adding the AWS MCP Server endpoint to Claude Code

Step 2: Review the authorization request

The first time your agent needs to access the AWS MCP Server, it opens a browser and redirects you to an AWS Sign-In page, shown in Figure 2. Authenticate as you would on AWS console or AWS CLI, review the authorization request, and approve access. You should receive an Authorization successful message.

Figure 2: Review authorization request

Figure 2: Review authorization request

Note that if you already have an active AWS Sign-In session (e.g., because you previously signed in to the console earlier in the day), you can reuse that session without needing to sign in again.

Step 3: Start using AWS tools

After connecting your agent to the AWS MCP Server, you can begin invoking tools provided by the server. To verify that Claude Code is connected to the AWS MCP Server, start Claude Code and run the following command:

/mcp

The command displays the configured MCP servers and confirms that the AWS MCP Server is connected and ready to use with your AWS credentials.

Figure 3 shows an example of a successful connection to the AWS MCP Server.

Figure 3: Verifying the AWS MCP Server connection in Claude Code

Figure 3: Verifying the AWS MCP Server connection in Claude Code

After the connection is established, you can ask Claude Code to invoke tools provided by the AWS MCP Server. For example, enter the following prompt:

Deploy a sample serverless web application into my development AWS account

Claude Code uses the AWS MCP Server to identify the active AWS account, confirm the target account, and describe the deployment it plans to perform before invoking AWS services on your behalf.

Figure 4 shows Claude Code confirming the active AWS account and outlining the resources that will be deployed.

Figure 4: Using Claude Code to deploy a sample serverless application through the AWS MCP Server

Figure 4: Using Claude Code to deploy a sample serverless application through the AWS MCP Server

Authorization models and how they work

AWS Sign-In supports two authorization models for connecting agents to the AWS MCP Server:

  • Interactive authorization for developer’s AI agents using browser based authentication
  • Non-interactive (headless) authorization for applications and AI agents that already have AWS credentials and don’t have access to a browser

Note that authorizing an agent allows it to access the AWS MCP Server on your behalf. It doesn’t grant the agent additional AWS permissions. Every request is still evaluated using your existing IAM policies, SCPs, RCPs, permission boundaries, and other organizational controls.

Interactive access

In the interactive case, the agent first discovers the AWS Sign-In OAuth server and then registers itself as an OAuth client using Dynamic Client Registration (DCR). It then redirects you to an AWS Sign-In page where you authenticate and authorize access (step 2 in the preceding section). After successful authorization, AWS Sign-In then issues short-lived access tokens and refresh tokens that authorize the agent to access the AWS MCP Server on your behalf. AWS Sign-In automatically manages token issuance and token refresh, enabling authorized agents to continue accessing the AWS MCP Server without requiring you to repeatedly sign in.

The interactive authorization model supports three distinct sign-in methods: native AWS IAM credentials for individual developers, managed access through AWS IAM Identity Center for enterprises, and seamless federated access via third-party providers like Okta and Ping Identity for larger organizations

OAuth server metadata and DCR

Before an agent can request authorization, it must discover the AWS Sign-In OAuth endpoints and register itself as an OAuth client. AWS Sign-In supports OAuth metadata discovery and DCR, allowing supported agents to configure themselves automatically without requiring developers to manually provision OAuth client IDs and client secretsWhen an agent connects to the AWS MCP Server for the first time, it retrieves the AWS MCP Server’s protected resource metadata (RFC 9728) and the AWS Sign-In OAuth metadata (RFC 8414). The agent then uses RFC 7591)) to register with AWS Sign-In, obtain a client ID, and initiate the standard OAuth authorization code flow.

AWS Sign-In supports OAuth discovery and DCR for agents running on local workstations and supported hosted environments. For the current list of supported agents and environments, see Supported redirect URIs for the AWS MCP Server.

Non-interactive access to the AWS MCP Server

Non-interactive (headless) authorization is for agents and applications that run without a browser or human in the loop, and thus don’t require interactive sign-in. This allows agents that already have AWS credentials to obtain OAuth access tokens and connect to the AWS MCP Server. The following is an example of how to obtain an access token.

aws signin create-oauth2-token-with-iam \ 
--grant-type client_credentials \ 
--resource aws-mcp.amazonaws.com \  
--region us-east-1 
{ 
"accessToken": "ASOA****************************************...", 
"tokenType": "Bearer", 
"expiresIn": 3600 
}

In the non-interactive case, AWS Sign-In implements the OAuth client credentials grant using AWS security credentials instead of a static client secret. Applications authenticate to the AWS Sign-In token endpoint using SigV4 creds, and AWS Sign-In returns a short-lived OAuth access token that can be used to access the AWS MCP Server.

Please note you may have to update the SDK and AWS CLI, please refer to CLI guide.

Managing OAuth access

AWS Sign-In extends the existing IAM authorization model with capabilities for governing OAuth access to the AWS MCP Server. Administrators can use familiar IAM policies together with new OAuth-specific controls.

Granting OAuth permissions

OAuth access is governed using IAM policies and requires the following IAM actions:

  • signin:AuthorizeOAuth2Access – Allows users to sign in interactively using the OAuth authorization code flow
  • signin:CreateOAuth2Token – Allows applications to obtain OAuth access tokens by exchanging authorization codes, refresh tokens, or using client credentials

When an application requests access, AWS Sign-In creates an OAuth authorization grant between the agent and the AWS MCP Server. This grant is represented as an IAM resource, which the preceding AWS Sign-In actions are authorized against.

arn:aws:signin:us-east-1:012345678910:service-principal/aws-mcp.amazonaws.com

OAuth authorization grants are represented as IAM resource enabling administrators to use standard IAM policy constructs, including global condition keys, together with OAuth-specific condition keys to control how authorization grants are created and used.

Governing OAuth access

AWS Sign-In introduces OAuth-specific condition keys that allow administrators to govern how agents obtain OAuth authorization. The following examples demonstrate common governance patterns.

To restrict OAuth authorization to localhost:

In addition to accessing the AWS MCP Server with agents on your local workstation, AWS supports signing into the AWS MCP Server on select hosted providers through dynamic client registration. Click here to view the list of supported remote providers. Many organizations want to allow developers to authorize agents running on their local workstations while preventing OAuth tokens from being delivered to untrusted redirect URIs or using unsupported authorization flows. The following policy allows only the OAuth authorization code and refresh token flows for the AWS MCP server and restricts token delivery tolocalhost.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "signin:AuthorizeOAuth2Access",
        "signin:CreateOAuth2Token"
      ],
      "Resource": "arn:aws:signin:*:*:service-principal/aws-mcp.amazonaws.com",
      "Condition": {
        "StringLike": {
          "signin:OAuthRedirectUri": "http://localhost:*"
        },
        "StringEquals": {
          "signin:OAuthGrantType": [
            "authorization_code",
            "refresh_token"
          ]
        }
      }
    }
  ]
}

To deny access for a specific OAuth session

Use the aws:SignInSessionArn global condition key to deny authorization associated with a specific sign-in session. This allows administrators to contain a suspicious or compromised authorization session without affecting other active sessions.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Action": [
        "*"
      ],
      "Resource": "*",
      "Condition": {
        "ArnEquals": {
          "aws:SignInSessionArn": "arn:aws:signin:us-east-1:111122223333:session/abc123-example-session-id"
        }
      }
    }
  ]
}

These examples demonstrate common governance patterns. Additional IAM and SCP examples are available in the AWS Sign-In condition keys reference.

Revoking OAuth tokens

AWS Sign-In provides OAuth token introspection and token revocation APIs that allow administrators to build custom tools for token validation and revocation. Access to these APIs is controlled through the signin:IntrospectOAuth2Token and signin:RevokeOAuth2Token permissions. IAM principals with permissions are allowed to introspect and revoke tokens for the same account.

The introspection API can be used to determine whether a token is active and obtain information about the associated authorization. The revocation API allows administrators and security tools to revoke individual refresh tokens without affecting other active sessions. For example, if an organization needs to invalidate access for a specific OAuth authorization, account admins can revoke the associated refresh token without affecting other active sessions.

Monitoring OAuth activity

OAuth-related activities are recorded in AWS CloudTrail, including authorization requests, token issuance, token revocation, and token introspection events. CloudTrail logs also capture details such as the OAuth client, target the AWS MCP Server, redirect URI, authorization flow, and associated sign-in session. In addition, AWS API calls made using OAuth access tokens include the associated aws:SignInSessionArn context, allowing organizations to correlate API activity with the originating OAuth sign-in session.

This allows security teams to monitor OAuth usage, investigate authorization activity, detect anomalous behavior, and integrate OAuth events into existing auditing, compliance, and incident response workflows alongside other AWS activity.

Here’s a CloudTrail sample for an AuthorizeOAuth2Access event:

{
    "eventVersion": "1.11",
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROATJHQDX737YZP****:testuser",
        "arn": "arn:aws:sts::111111111111:assumed-role/Admin/testuser",
        "accountId": "111111111111",
        "sessionContext": {
            "sessionIssuer": {
                "type": "Role",
                "principalId": "AROA2IRT4N5U4RDHM2LG4",
                "arn": "arn:aws:iam::111111111111:role/Admin",
                "accountId": "111111111111",
                "userName": "Admin"
            },
            "attributes": {
                "creationDate": "2026-06-09T05:06:39Z",
                "mfaAuthenticated": "false"
            }
        }
    },
    "eventTime": "2026-06-09T05:09:00Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "AuthorizeOAuth2Access",
    "awsRegion": "us-west-2",
    "sourceIPAddress": "192.0.0.2",
    "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/149.0.0.0 Safari/537.36",
    "requestParameters": {
        "resource": "https://aws-mcp.us-west-2.api.aws/mcp",
        "redirect_uri": "http://127.0.0.1:60432/oauth/callback",
        "code_challenge_method": "S256",
        "client_id": "arn:aws:signin:us-west-2::external-client/dcr/609544da-aasa-49a4-ab11-c2r457fa999"
    },
    "responseElements": null,
    "additionalEventData": {
        "success": "true"
    },
    "requestID": "4fb4ff7b-6yu7-9090-78i9-9c0088a65134",
    "eventID": "bb05b222-31ec-4237-b8e7-8eb26d4fd48b",
    "readOnly": true,
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": "111111111111",
    "eventCategory": "Management",
    "tlsDetails": {
        "tlsVersion": "TLSv1.3",
        "cipherSuite": "TLS_AES_128_GCM_SHA256",
        "clientProvidedHostHeader": "us-west-2.oauth.signin.aws"
    }
}

Here’s a CloudTrail sample for a CreateOAuth2Token event:

{
    "eventVersion": "1.11",
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROATJHQDX737YZP7****:testuser",
        "arn": "arn:aws:sts::111111111111:assumed-role/Admin/testuser",
        "accountId": "111111111111",
        "sessionContext": {
            "sessionIssuer": {
                "type": "Role",
                "principalId": "AROA2IRT4N5U4RDHM****",
                "arn": "arn:aws:iam::111111111111:role/Admin",
                "accountId": "111111111111",
                "userName": "Admin"
            },
            "attributes": {
                "creationDate": "2026-06-09T05:06:39Z",
                "mfaAuthenticated": "false"
            },
            "signInSessionArn":""
            
        }
    },
    "eventTime": "2026-06-09T05:10:04Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "CreateOAuth2Token",
    "awsRegion": "us-west-2",
    "sourceIPAddress": "192.0.0.2",
    "userAgent": "curl/8.7.1",
    "requestParameters": {
        "resource": "https://aws-mcp.us-west-2.api.aws/mcp",
        "client_id": "arn:aws:signin:us-west-2::external-client/dcr/609544da-b3dd-49a4-ab11-c2e98d7fa999"
    },
    "responseElements": null,
    "additionalEventData": {
        "signInSessionArn": "arn:aws:signin:us-west-2:111111111111:session/daff060f-7871-5tg6-67yu-a07bbdabe61a",
        "grant_type": "refresh_token",
        "success": "true"
    },
    "requestID": "44d6d7ce-e4r5-4cbf-0909-bfb8a8295a76",
    "eventID": "f79cc63f-b383-4e3c-a1e5-97c7db1ab833",
    "readOnly": true,
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": "111111111111",
    "eventCategory": "Management",
    "tlsDetails": {
        "tlsVersion": "TLSv1.3",
        "cipherSuite": "TLS_AES_128_GCM_SHA256",
        "clientProvidedHostHeader": "us-west-2.oauth.signin.aws"
    }
}

Additional audit events and logging details for calls made using OAuth access tokens to the AWS MCP Server can be found in Logging AWS MCP Server API calls using AWS CloudTrail.

Conclusion

AWS Sign-In support for OAuth enables you to securely connect to the AWS MCP Server using industry-standard authorization. This release simplifies application and agent integration with AWS while supporting your existing IAM setup, governance, and auditing capabilities.

To learn more, see Sign-In with OAuth 2.0 in the AWS Sign-In User Guide and Setting up the AWS MCP Server in the Agent Toolkit for AWS User Guide.

If you have feedback about this post, submit comments in the Comments section below.


Vaibhav Chowla

Vaibhav Chowla

Vaibhav is a Senior Technical Product Manager at AWS, specializing in AWS Identity products. He focuses on enhancing user authentication and security, helping customers of all sizes solve complex identity and access management (IAM) challenges. Outside of technology, Vaibhav enjoys traveling and exploring new cultures and cuisines.

Jaimin Bhatt

Jaimin Bhatt

Jaimin is a Principal Software Engineer at AWS. He works on AWS Identity and Access Management (IAM) across sign-in, threat detection, and the authentication and authorization that secures access to AWS. Jaimin is an active participant in multiple industry standards bodies. Previously, he led work on data perimeter controls for AWS Management Console sign-in, multi-session support for the console, a simplified AWS CLI sign-in experience, and the internal Amazon identity provider.

Ankur Joshi

Ankur Joshi

Ankur is a Software Development Manager on the AWS Identity Sign-In team. His team focuses on delivering secure and resilient authentication mechanisms and access controls for AWS customers.

Specification-driven composition for flexible data workflows

Post Syndicated from Rostislav Markov original https://aws.amazon.com/blogs/architecture/specification-driven-composition-for-flexible-data-workflows/

Specification-driven composition addresses a common scalability bottleneck in data pipelines. Data pipelines often start as simple scripts, but as they grow, you duplicate transformation logic and small changes cascade across multiple workflows. Copying and modifying data transformation logic across scripts leads to workflows that become difficult to manage at scale. Tracking what each pipeline does becomes harder because workflow intent is embedded in code. This lack of visibility complicates governance, especially in regulated environments such as healthcare, finance, and life sciences.

Many implementations combine orchestration, transformation logic, and validation rules in the same scripts. Supporting new datasets requires modifying and redeploying code, while validation often happens only during processing. As a result, issues surface late in the lifecycle which increases the operational risk. Specification-driven composition separates workflow intent from implementation so you can build flexible data workflows.

In this post, I show how to apply specification-driven composition to data transformation workflows. I explain the challenges with script-based pipelines, introduce the pattern and its core components, and walk through a serverless implementation using AWS Lambda, AWS Step Functions, Amazon Simple Storage Service (Amazon S3), and Amazon OpenSearch Service.

Solution overview

You can separate workflow intent from processing logic with specification-driven composition. This approach reduces duplication, shortens the time required to onboard new datasets, and improves consistency across workflows. Instead of embedding logic in scripts, the system describes workflow intent in a structured specification, validates the specification before processing, and dynamically assembles a processing pipeline.

This approach moves pipeline configuration outside application code and composes pipelines from reusable processing components. To separate concerns, it organizes a workflow into three layers, as shown in Figure 1. The intent layer defines workflow behavior using specifications. The composition layer validates specifications and assembles pipelines. The processing layer runs the pipeline of transformation steps.

A diagram showing the three layers of specification-driven composition. The intent layer holds the specification, the composition layer contains the composer and capability registry, and the processing layer runs the capability pipeline.

Figure 1. Specification-Driven Composition design pattern.

Benefits

Specification-driven composition provides several practical benefits when you manage multiple pipelines. First, it improves governance because specifications provide a clear, traceable description of workflow behavior that you can review and validate before invocation. In regulated industries, this traceability shortens audit preparation time and reduces the review burden for new dataset submissions.

Second, the pattern supports reusable transformations. You implement transformation logic once and reuse it across multiple workflows. This reduces duplication and improves consistency. In practice, teams adopting this pattern report being able to onboard new datasets in days rather than weeks because most required capabilities already exist in the registry.

Third, specification-driven composition enables flexible pipeline design. You define new specifications to create pipelines supporting new datasets and use cases without modifying application code and registering new system release.

Fourth, the pattern separates business intent from execution artifacts. The specification expresses what the workflow should do in domain terms, while the generated state machine remains a system artifact. This separation matters in regulated environments (for example, GxP) where business users author intent but are not allowed to author or modify execution code directly.

Finally, the declarative representation of workflows lets AI tools assist with capability discovery, specification authoring, and pipeline analysis, while runtime behavior stays predictable as it relies on validated capabilities.

Core components

You work with four key components to define, validate, and run workflows.

  1. Specification

A specification is a structured document, typically JSON or YAML, that describes datasets, mappings, and transformations. It defines what the workflow should do without including processing logic. Because specifications are explicit and versioned, they provide a clear record of workflow intent.

  1. Composer

The composer converts specifications into runnable steps, so workflows run consistently without embedding transformation logic in application code. It checks that referenced capabilities exist, retrieves metadata, and builds a workflow that can run on the processing layer. The composer does not perform transformations. It only assembles the workflow. In practice, the composer compiles business intent expressed in the specification into a code artifact such as an Amazon States Language (ASL) definition. This abstraction lets domain users author specifications without producing runnable code, which is important in environments with strict separation of duties.

  1. Capability registry

The registry stores metadata about reusable transformation functions. This includes identifiers, input/output formats, invocation details, and permission boundaries. The composer uses the registry to validate specifications and locate capabilities. Treat this registry as a governed artifact rather than a manually edited lookup table. Capability definitions live in version control, and your CI/CD pipeline validates metadata and runs tests before you publish new versions. Specification authors include explicit capability version references in the specifications to support reproducible workflow runs. In regulated systems, you must validate new capabilities and obtain approval through a separate workflow before you register them.

  1. Capability pipeline

Once assembled, the pipeline runs a sequence of transformation steps. Each step performs a specific operation such as formatting, validation, or enrichment. Because these steps are reusable, you can apply them across many workflows.

Technical implementation

Let’s walk through a technical implementation of this pattern using serverless AWS services. In this example, workflow specifications are uploaded to an S3 bucket. An AWS Lambda composer retrieves and validates the specification, looking up capability metadata in Amazon OpenSearch Service. The composer then assembles the workflow in AWS Step Functions, which orchestrates the workflow and invokes AWS Lambda capability processors. Each processor emits traces to Amazon CloudWatch Logs.

Figure 2 shows the architecture.

Users upload specifications to Amazon S3, which invokes the Lambda composer. The composer queries the OpenSearch registry and assembles a Step Functions workflow of Lambda capability processors, which emit traces to CloudWatch.

Figure 2. AWS implementation of Specification-Driven Composition

Interpreting the workflow specification

The workflow specification defines datasets and transformation logic using a structured format (in this example, JSON). A specification is a declarative document that describes what the pipeline should produce rather than how to produce it. Your composer reads the specification, validates it against a schema, and uses it to construct the pipeline.

The following example maps source fields to target fields using reusable capabilities (Figure 3). It takes data from a source dataset (‘raw_orders’), maps specific fields (‘order_date’, ‘amount’) and applies reusable transformation capabilities such as ‘format_date’ and ‘normalize_currency’. Each mapping explicitly links a source field to a target field and references a capability that performs the transformation. Source dataset(s) are listed under the ‘source’ section of the JSON document, target datasets under the ‘target’ section, and mappings ‘mappings’. You can define your own specification structure and build custom validation logic in your composer to make sure specifications are valid.

{
  "source": {
    "dataset": "raw_orders"
  },
  "target": {
    "dataset": "orders_clean"
  },
  "mappings": [
    {
      "source_field": "order_date",
      "target_field": "order_date",
      "transformation": {
        "capability": "format_date"
      }
    },
    {
      "source_field": "amount",
      "target_field": "amount_normalized",
      "transformation": {
        "capability": "normalize_currency"
      }
    }
  ]
}

You can model preprocessing steps such as column standardization, numeric casting, or unit conversion as first-class capabilities and reference them earlier in the specification (for example, in a dedicated ‘preprocessing’ section) before downstream mappings run. This way, preparation logic uses the same metadata, versioning, validation, and observability model as the rest of the workflow, which simplifies lineage and review.

In this example, an S3 event notification invokes the composer Lambda function when you upload a specification. In practice, the same composer can be invoked through several mechanisms depending on the use case: S3 events for new specifications, an Amazon EventBridge schedule for recurring runs, an API or UI action for on-demand invocation, a direct Step Functions StartExecution call, or an upstream pipeline. This flexibility lets you re-run an approved specification against refreshed data without re-authoring or re-approving the workflow.

The composer parses the specification and validates the referenced capabilities by querying Amazon OpenSearch Service to retrieve capability metadata such as Amazon Resource Names (ARNs). OpenSearch Service is used here because the composer does more than direct-key lookups. It supports capability discovery through full-text and semantic search over capability metadata such as capability descriptions, input/output schemas, and tags. This lets data authors and AI tools find reusable capabilities by intent rather than by exact identifier. After validation, the composer assembles and starts an AWS Step Functions state machine which invokes each capability in sequence. Each capability runs independently, making the pipeline modular and reusable.

Securing sensitive data flows

This pattern suits regulated workloads, so handle security as part of the design. Use SSE-KMS with a customer managed key on the specification and data S3 buckets and enable encryption at rest on the Amazon OpenSearch Service domain. Enforce HTTPS (TLS) access with an S3 bucket policy (aws:SecureTransport) and enable node-to-node encryption on Amazon OpenSearch Service. AWS Step Functions and Lambda calls use TLS by default. Each capability processor receives only the fields its mapping references, and you can apply IAM policy at the source bucket to restrict access. Processors emit traces to Amazon CloudWatch Logs.

For data classification, you can tag sensitive fields in the specification (example: "sensitivity": "PHI") and declare the sensitivity of each capability in the registry: a direct-move capability preserves the source classification, a date-of-birth-to-age capability clears it, and an enrichment that introduces sensitive data sets it. The composer combines the source tag with the capability’s behavior to derive the target field’s sensitivity, validating that the combination resolves clearly before assembling the pipeline. It then generates the masking artifact for the output (for example, AWS Lake Formation column grants) so consumers get correct masking without a separate masking specification or manual effort.

Recognizing the pattern

This approach works well when you describe workflows using structured specifications, reuse transformation logic across pipelines, require validation before invocation, and require workflows to be deterministic and auditable. You are likely to recognize the pattern in regulated data pipelines for the submission of tabular datasets to oversight agencies.

Consider clinical trial reporting as a concrete example. Data analysts collect raw data from clinical sites and must transform it into a standard submission format such as the Study Data Tabulation Model (SDTM) before submission to agencies such as the US Food and Drug Administration. With specification-driven composition, data analysts define specifications that map collected data about adverse events, demographics, and vital signs to the standard target variables, and the validated output feeds downstream systems such as patient safety and medical monitoring.

That said, this pattern might add unnecessary complexity for simple, one-time data transformations or pipelines with fewer than three to five workflows. Evaluate this pattern’s impact by tracking the reduction in duplicated transformation logic across pipelines, the time required to onboard new datasets, and the number of workflows you can create without modifying application code.

Conclusion

Script-based data pipelines accumulate hidden costs as they grow, including duplicated logic across files and late-breaking validation failures. Specification-driven composition separates workflow intent from processing so you can manage data workflows more consistently at scale. The result is faster dataset onboarding, stronger governance, and pipelines that are transparent enough to trust in regulated environments.

This pattern is especially valuable for regulated reporting pipelines, multi-source data integration, and reusable ETL frameworks where traceability and flexibility matter. By investing a small set of reusable capabilities and a disciplined specification format, you can reduce the engineering effort for new pipelines by treating them more as configuration tasks which may be delegated to system users.

Next steps

To get started, take one existing pipeline and describe it as a specification. Implement a small set of reusable transformation functions and use them to assemble your first composed workflow. The AWS Lambda event-driven architectures guide is a good starting point for wiring S3 uploads to your composer, and the AWS Step Functions and Lambda integration guide will help you orchestrate your capability processors. To monitor the pipeline, see publishing custom CloudWatch metrics.

For a practical first use case, try applying the pattern to a reporting pipeline you maintain today that has three or more variants such as monthly finance reports generated from different source systems. Replace the duplicated scripts with a single composer and a shared capability library, and measure the onboarding time for the next variant. As you expand your capability library, you can apply the same pattern across additional workflows and standardize how transformations are defined and run.


About the author

THIS is the Best Way to Watch Sports at Cosm Los Angeles and We Toured the Technology Behind it

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/we-tour-the-dell-it-behind-the-best-way-to-watch-sports-at-cosm-los-angeles/

We take you on a behind-the-scenes tour of Cosm Los Angeles to see what is possibly the best way to experience watching live sports

The post THIS is the Best Way to Watch Sports at Cosm Los Angeles and We Toured the Technology Behind it appeared first on ServeTheHome.

The collective thoughts of the interwebz