What’s in Store at Summit ‘24?

Post Syndicated from Michael Kammer original https://blog.zabbix.com/whats-in-store-at-summit-24/28649/

October means different things to different people – it’s springtime in the Southern Hemisphere, autumn in the Northern Hemisphere, and Summit time if you’re a member of the Zabbix community! Summit time, of course, means the biggest of all Zabbix events, gathering the global Zabbix community in one place to have fun together and learn as much as we can from each other. Zabbix Summit 2024 will take place on October 3-5 in Riga at the Radisson Blu Hotel Latvija. Keep reading to find out more about what you can expect this year.

All new main stage presentations

During Zabbix Summit 2024, you’ll be able to catch a variety of presentations from top industry thought leaders. You’ll learn all about the latest Zabbix features, explore use cases from multiple industries, check out the latest integrations, and have the chance to get your questions answered during live Q&A sessions.

The Summit agenda will feature speeches on nearly any Zabbix-related topic that you can imagine, but this year we’ll also have a fresh focus on the potential of artificial intelligence, with presentations on topics like “New Approaches to Reduce Alert Noise with Zabbix and AIOps” and “Leveraging AI for Synthetic Web Monitoring” as well as a more business-focused group of speeches covering topics related to open-source integration and Zabbix for MSPs.

Hands-on learning in Zabbix Summit workshops

Zabbix Summit workshops are the ideal place to put the theory you learn during presentations into practice. You can check out the latest features and use cases in action, while performing a variety of real-world tasks under the guidance of workshop hosts and their assistants – many of whom are also featured presenters at this year’s Summit.

All you’ll need to do is bring your own laptop – depending on the topic covered in the particular workshop, an SSH client and a web browser may also be required. All workshop sessions will take place on the morning of October 5 (Day 2 of the Summit) and will begin at 10AM.

Zabbix Certified Training sessions and exams

Do you have a lifetime of monitoring experience, but are too shy to let everyone know it? When you attend Zabbix Summit 2024, you’ll be able to prove your skills as a Zabbix specialist or professional by taking part in Zabbix Certified Training sessions and exams. If you’re looking for more specific topics to dive into, the following one-day courses will also be held from October 2 through October 4:

  • Automation and Integration with Zabbix API
  • Advanced Problem and Anomaly Detection with Zabbix
  • Advanced Zabbix Data Pre-Processing
  • Advanced Zabbix SNMP Monitoring

If you don’t mind extending your stay in Riga just a bit longer (and seriously, why would you?), you’ll also be able to take the full Zabbix Certified Specialist or Professional courses scheduled for October 9-13. Please remember that you can choose more than one training course, and it’s possible to attend the courses (without the 10% Summit discount) even if you’re not attending the Summit.

You can sign up for all training sessions and exams here.

The Zabbix Summit Feedback and Testimonial corner

Just as at last year’s Summit, you’ll be able to share your Zabbix story with the rest of the Zabbix community at our Feedback and Testimonial corner. Sharing a testimonial or leaving a review will give you a chance to collect a piece of exclusive Zabbix Summit 2024 merchandise!

Exclusive items, cool new designs, and unique gadgets at our merchandise shop

Speaking of merch, you’ll be pleased to know that not only will exclusive Zabbix Summit merchandise be available at a special stand throughout the event, but we’ll also have an online platform that will allow you to pre-order your merchandise and pick it up at the Summit. We’ve got 5 exclusive new t-shirt designs, 4 fresh sock designs, brand-new beanies, and the usual assortment of gadgets, hoodies, and other merch that our fans have come to know and love – most of which has also gotten a new look for this year’s Summit as well.

Three incredible Zabbix Summit 2024 networking events

There’s a lot to take in and consider at a Zabbix Summit, but don’t worry – we’ve also made sure to give you plenty of time to network with your fellow Zabbix fans by organizing three big events that you won’t want to miss!

  • The Zabbix Summit 2024 welcome event will be held at the famous National Library of Latvia – or as Latvians call it, “The Castle of Light.” You’ll enjoy tasty beverages, delicious food, and a guided tour of the library as you mingle with fellow Zabbix enthusiasts and industry experts, making this the perfect way to kick off this year’s Summit.
  • You’ll want to prepare yourself for a truly unforgettable experience as the Zabbix Summit main event unfolds. We’re sure that you’ll find Riga’s famous Fantadroms Concert and Event Space to be the ideal place to forge valuable connections with like-minded professionals – while indulging in a unique array of culinary delights, refreshing beverages, and great music.
  • After all that, we’ll send you on your way with a closing event that will be the perfect grand finale to a Summit that you won’t soon forget! Located in the heart of Old Riga, Burzma is a food hall that spans 1,500 square meters across the entire fourth floor of a bustling shopping mall. With stunning rooftop views to inspire your dining experience, Burzma offers 10 restaurants and a bar serving up a diverse range of culinary delights.

A chance to see where the magic happens during our Open-Door day

In what has become a popular tradition, Zabbix will host an Open-Door day on Thursday, October 3 from 1PM to 3PM local time. You’ll be able to chat with Zabbix team members, tour our headquarters, and take part in a fun activity designed to help you learn more about Zabbix.

Booths galore!

As usual, the Zabbix team will have multiple booths in the conference hall where you can meet our engineers and developers and get your questions answered by the people who know best. Our Summit sponsors will have booths of their own as well, where you can enjoy a unique opportunity to interact with them on a personal level and get the lowdown on the solutions they offer.

Special events for support customers

All Zabbix support customers are invited to meet our team at a special Zabbix client lunch on October 3 at 14:00 (EEST), with the exact location to be announced at a later date. What’s more, Enterprise and Global support customers are also invited to the Zabbix roadmap Q&A session with Zabbix CEO and Founder Alexei Vladishev on October 5 at 10AM. You’ll learn about our software development plans and be able to raise questions or make suggestions based on your experience – definitely an opportunity you won’t want to miss!

Which Zabbix Summit ticket is right for you?

If you want to enjoy the full Zabbix Summit experience (conference, accommodation, food, even airport transfers), the Full Participation ticket package is definitely for you.

For loyal users who have contributed so much to our product over the years, the Zabbix Fan package is definitely the way to go – it includes everything you’ll get with the Full Participation package, plus a special official fan package that will guarantee you bragging rights in your office once you return from Riga.

If you’re only there for the sessions, the Hall only pass is ideal. If you enjoy both learning and networking with our team and enthusiasts from around the world, we think you’ll find the Hall and Networking pass to be perfect for your needs.

Want to bring a friend or partner along to the summit? No problem — get a Zabbix Summit Travel Companion pass for them so you can stay together and attend networking events, while we handle the rest of their Riga experience.

The Companion pass includes 3 nights’ accommodation in the Radisson Blu Latvija hotel (in the same room as the Summit attendee), 3 breakfasts, and 3 networking events, but that’s not all – we’ll also include an exclusive tour of Riga on October 4 with an English-speaking guide.

The tour features a visit to the Ethnographic Open-Air Museum of Latvia, and runs from approximately 10AM to 4PM, including lunch and some workshop activities at the museum. You can learn more about the museum here.

Visit this page to sign up for the ticket package of your choice.

Livestreaming on YouTube

We hope to see you soon in Riga, but if you can’t make it, don’t worry – as in previous years, we’re going to be livestreaming the speeches on our YouTube channel! Stay tuned for more details.

The post What’s in Store at Summit ‘24? appeared first on Zabbix Blog.

Broadcom AI Compute ASIC with Optical Attach Detailed at Hot Chips 2024

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/broadcom-ai-compute-asic-with-optical-attach-detailed-at-hot-chips-2024/

In one of the coolest presentations at Hot Chips 2024 so far, Broadcom showed co-packaged silicon photonics for switches and AI ASICs

The post Broadcom AI Compute ASIC with Optical Attach Detailed at Hot Chips 2024 appeared first on ServeTheHome.

Chimera Sandbox: A scalable experimentation and development platform for Notebook services

Post Syndicated from Grab Tech original https://engineering.grab.com/chimera-sandbox

Key to innovation and improvement in machine learning (ML) models is the ability for rapid iteration. Our team, Chimera, part of the Artificial Intelligence (AI) Platform team, provides the essential compute infrastructure, ML pipeline components, and backend services. This support enables our ML engineers, data scientists, and data analysts to efficiently experiment and develop ML solutions at scale.

With a commitment to leveraging the latest Generative AI (GenAI) technologies, Grab is enhancing productivity tools for all Grabbers. Our Chimera Sandbox, a scalable Notebook platform, facilitates swift experimentation and development of ML solutions, offering deep integration with our AI Gateway. This enables easy access to various Large Language Models (LLMs) (both proprietary and open source), ensuring scalability, compliance, and access control are managed seamlessly.

What is Chimera Sandbox?

Chimera Sandbox is a Notebook service platform. It allows users to launch multiple notebook and visualisation services for experimentation and development. The platform offers an extremely quick onboarding process enabling any Grabber to start learning, exploring and experimenting in just a few minutes. This inclusivity and ease of use have been key in driving the adoption of the platform across different teams within Grab and empowering all Grabbers to be GenAI-ready.

One significant challenge in harnessing ML for innovation, whether for technical experts or non-technical enthusiasts, has been the accessibility of resources. This includes GPU instances and specialised services for developing LLM-powered applications. Chimera Sandbox addresses this head-on by offering an extensive array of compute instances, both with and without GPU support, thus removing barriers to experimentation. Its deep integration with Grab’s suite of internal ML tools transforms the way users approach ML projects. Users benefit from features like hyperparameter tuning, tracking ML training metadata, accessing diverse LLMs through Grab’s AI Gateway, and experimenting with rich datasets from Grab’s data lake. Chimera Sandbox ensures that users have everything they need at their fingertips. This ecosystem not only accelerates the development process but also encourages innovative approaches to solving complex problems.

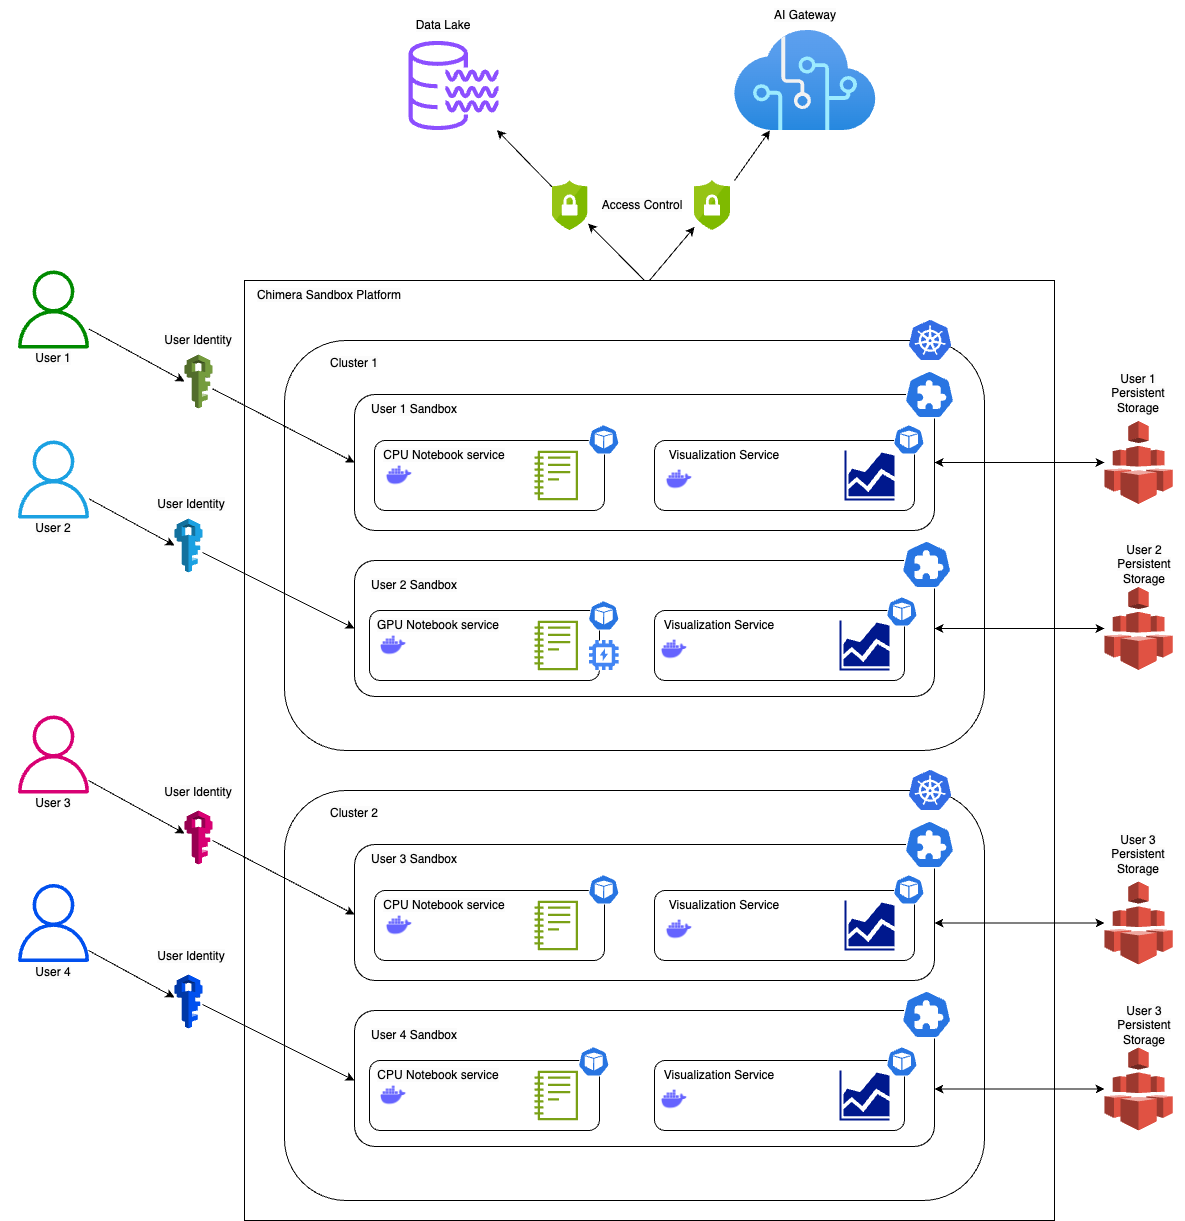
The underlying compute infrastructure of the Chimera Sandbox platform is Grab’s very own battle-tested, highly scalable ML compute infrastructure running on multiple Kubernetes clusters. Each cluster can scale up to thousands of nodes at peak times gracefully. This scalability ensures that the platform can handle the high computational demands of ML tasks. The robustness of Kubernetes ensures that the platform remains stable, reliable, and highly available even under heavy load. At any point in time, there can be hundreds of data scientists, ML engineers and developers experimenting and developing on the Chimera Sandbox platform.

Figure 1. Chimera Sandbox Platform.
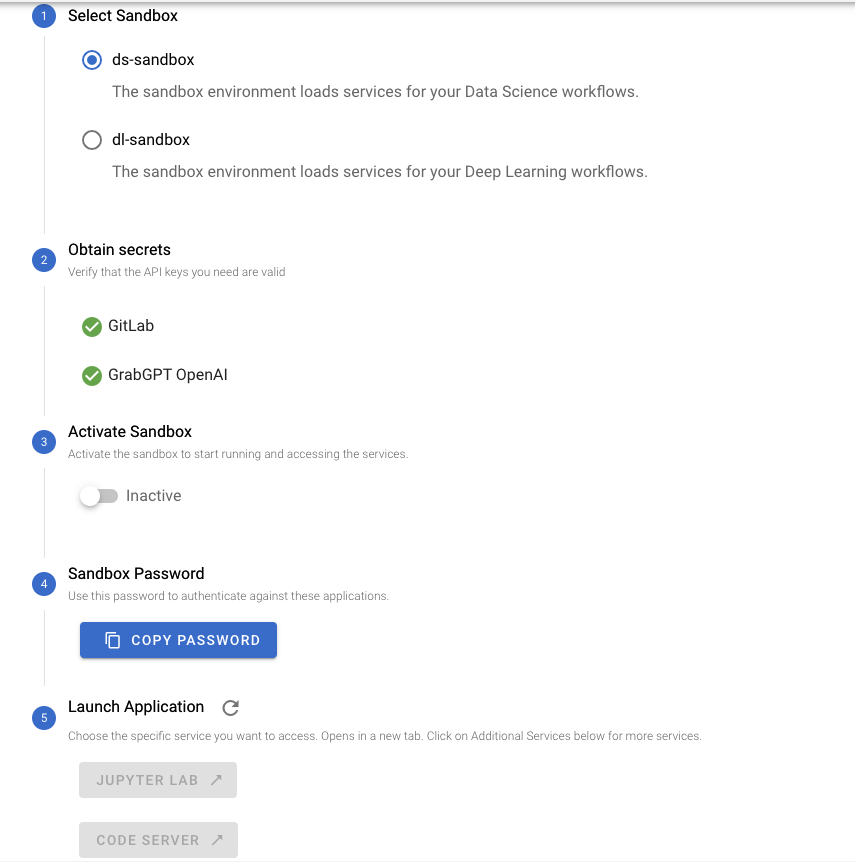
Figure 2. UI for Starting Chimera Sandbox.

Best of both worlds

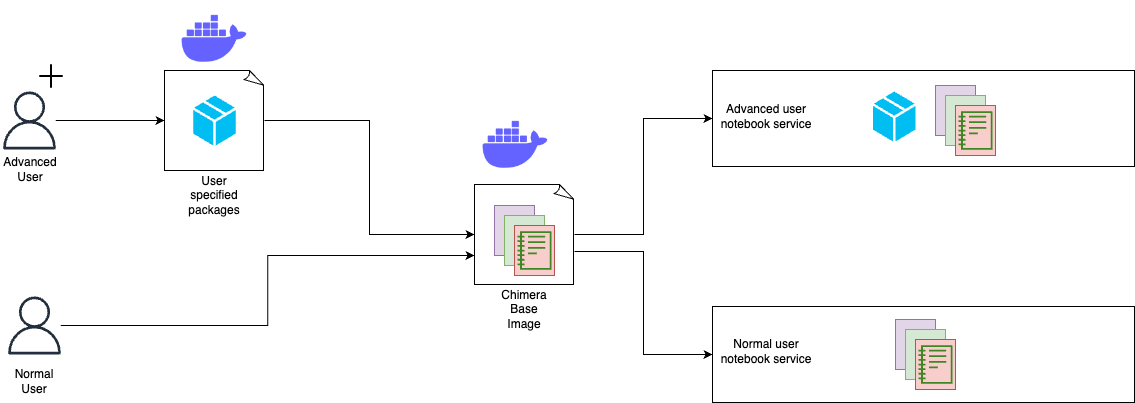
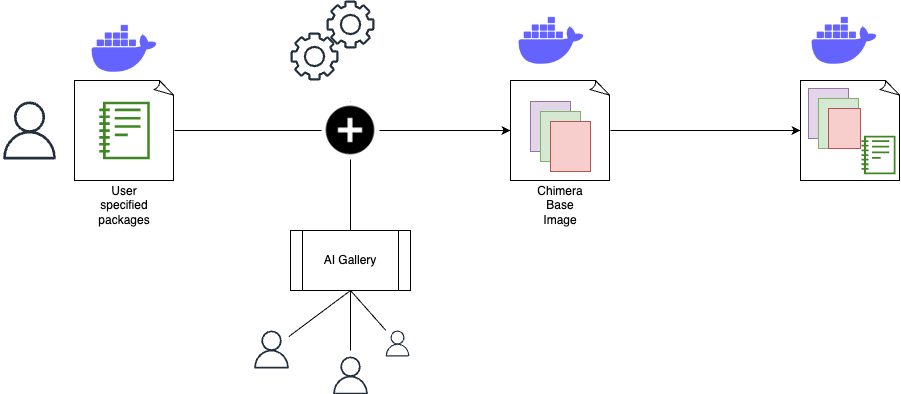
Chimera Sandbox is suitable for both new users who want to explore and experiment ML solutions and advanced users who want to have full control over the Notebook services they run. Users can launch Notebook services using default Docker images provided by the Chimera Sandbox platform. These images come pre-loaded with popular data science and ML libraries and various Grab internal systems integrations. Chimera also provides basic Docker images from which the users can use as base images to build their own customised Notebook service Docker images. Once the images are built, the users can configure their Notebook services to use their custom Docker images. This ensures their Notebook environment can be exactly the way they want them to be.

Figure 3. Users are able to customise their Notebook service with additional packages.

Real-time collaboration

The Chimera Sandbox platform also features a real-time collaboration feature. This feature fosters a collaborative environment where users can exchange ideas and work together on projects.

CPU and GPU choices

Chimera Sandbox offers a wide variety of CPU and GPU choices to cater to specific needs, whether it is a CPU, memory, or GPU intensive experimentation. This flexibility allows users to choose the most suitable computational resources for their tasks, ensuring optimal performance and efficiency.

Deep integration with Spark

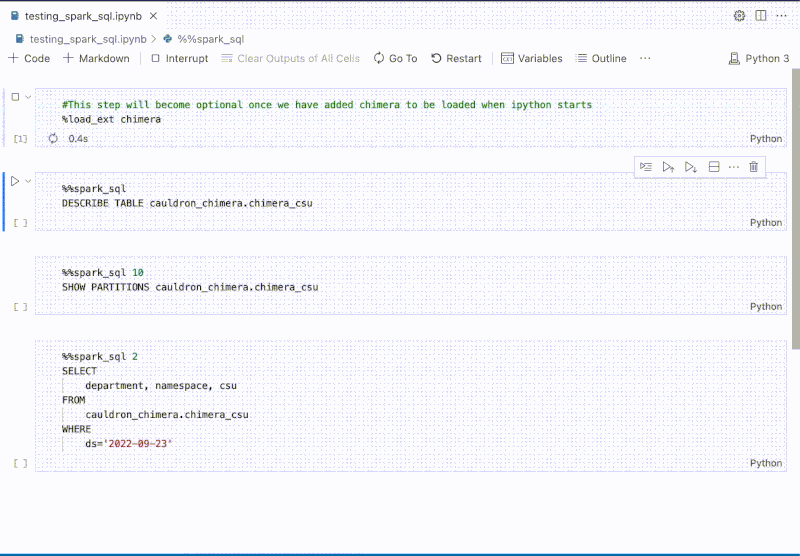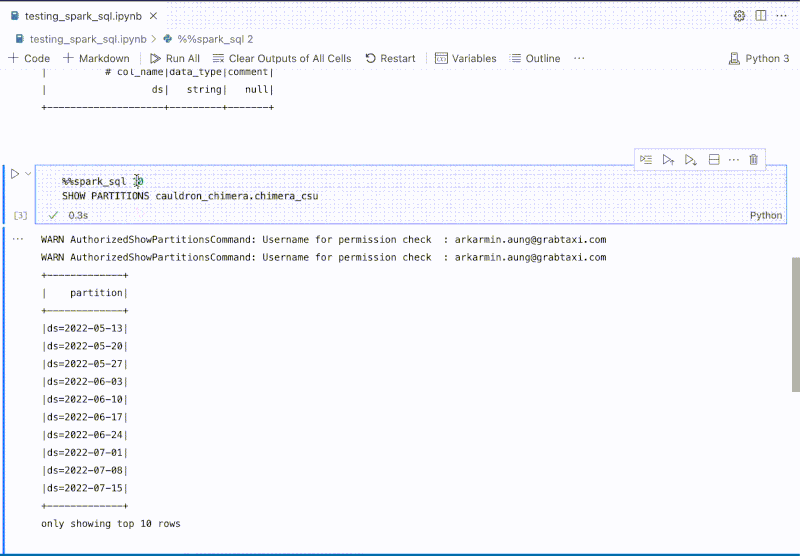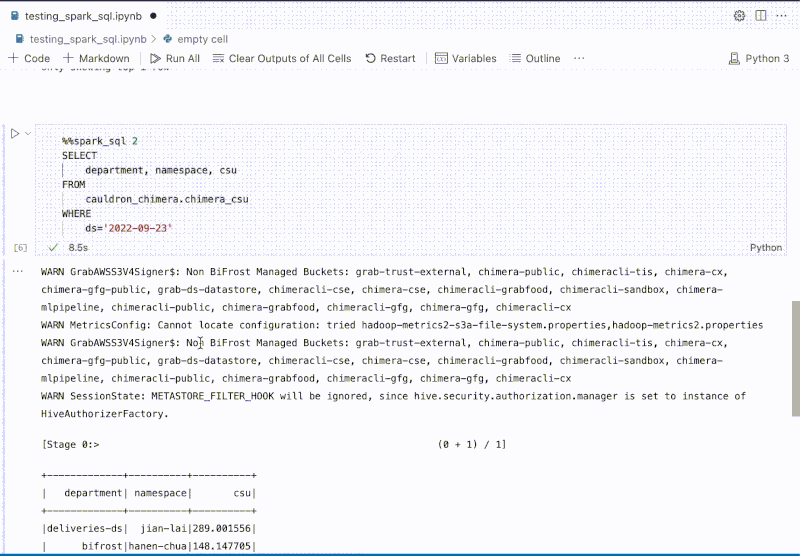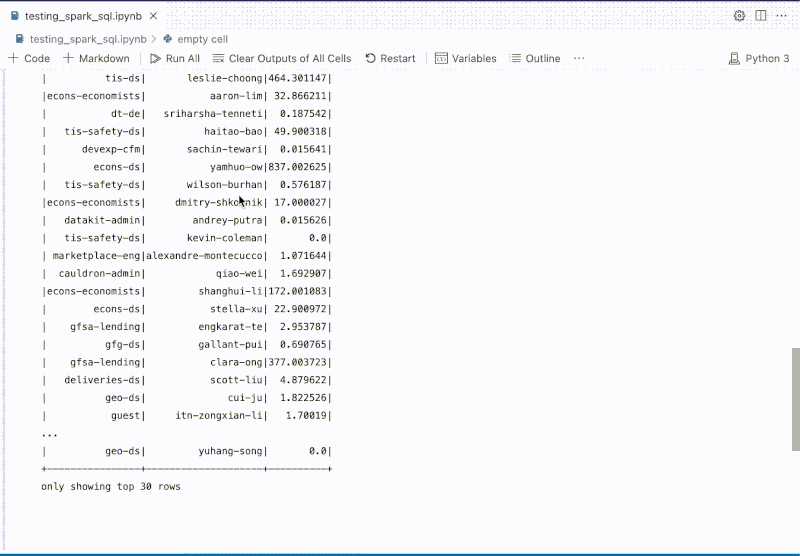
The platform is deeply integrated with internal Spark engines, enabling users to experiment building extract, transform, and load (ETL) jobs with data from Grab’s data lake. Integrated helpers such as SparkConnect Kernel and %%spark_sql magic cell, provide a faster developer experience, which can execute Spark SQL queries without needing to write additional code to start a Spark session and query.

Figure 4. %%spark_sql magic cell enables users to quickly explore data with Spark.

In addition to Magic Cell, the Chimera Sandbox offers advanced Spark functionalities. Users can write PySpark code using pre-configured and configurable Spark clients in the runtime environment. The underlying computation engine leverages Grab’s custom Spark-on-Kubernetes operator, enabling support for large-scale Spark workloads. This high-code capability complements the low-code Magic Cell feature, providing users with a versatile data processing environment.

Chimera Sandbox features an AI Gallery to guide and accelerate users to start experimenting with ML solutions or building GenAI-powered applications. This is especially useful for new or novice users who are keen to explore what they can do on the Chimera Sandbox platform. With Chimera Sandbox, users are not just presented with a bare bones compute solution but rather are provided with ways to do ML tasks right from Chimera Sandbox Notebooks. This approach saves users from the hassle of having to piece together the examples from the public internet, which may not work on the platform. These ready-to-run and comprehensive notebooks in the AI Gallery assure users that they can run end-to-end examples without a hitch. Based on these examples, the users can only extend their experimentations and development for their specific needs. Not only that, these tutorials and notebooks exhibit the platform capabilities and integrations available on the platform in an interactive manner rather than having the users refer to a separate documentation.

Lastly, the AI Gallery encourages contributions from other Grabbers, fostering a collaborative environment. Users who are enthusiastic about creating educational contents on Chimera Sandbox can effectively share their work with other Grabbers.

Figure 5. Including AI Gallery in user specified sandbox images.

Integration with various LLM services

Notebook users on Chimera Sandbox can easily tap into a plethora of LLMs, both open source and proprietary models, without any additional setup via our AI Gateway. The platform takes care of access mechanisms and endpoints for various LLM services so that the users can easily use their favourite libraries to create LLM-powered applications and conduct experimentations. This seamless integration with LLMs enables users to focus on their GAI-powered ideas rather than having to worry about underlying logistics and technicalities of using different LLMs.

More than a notebook service

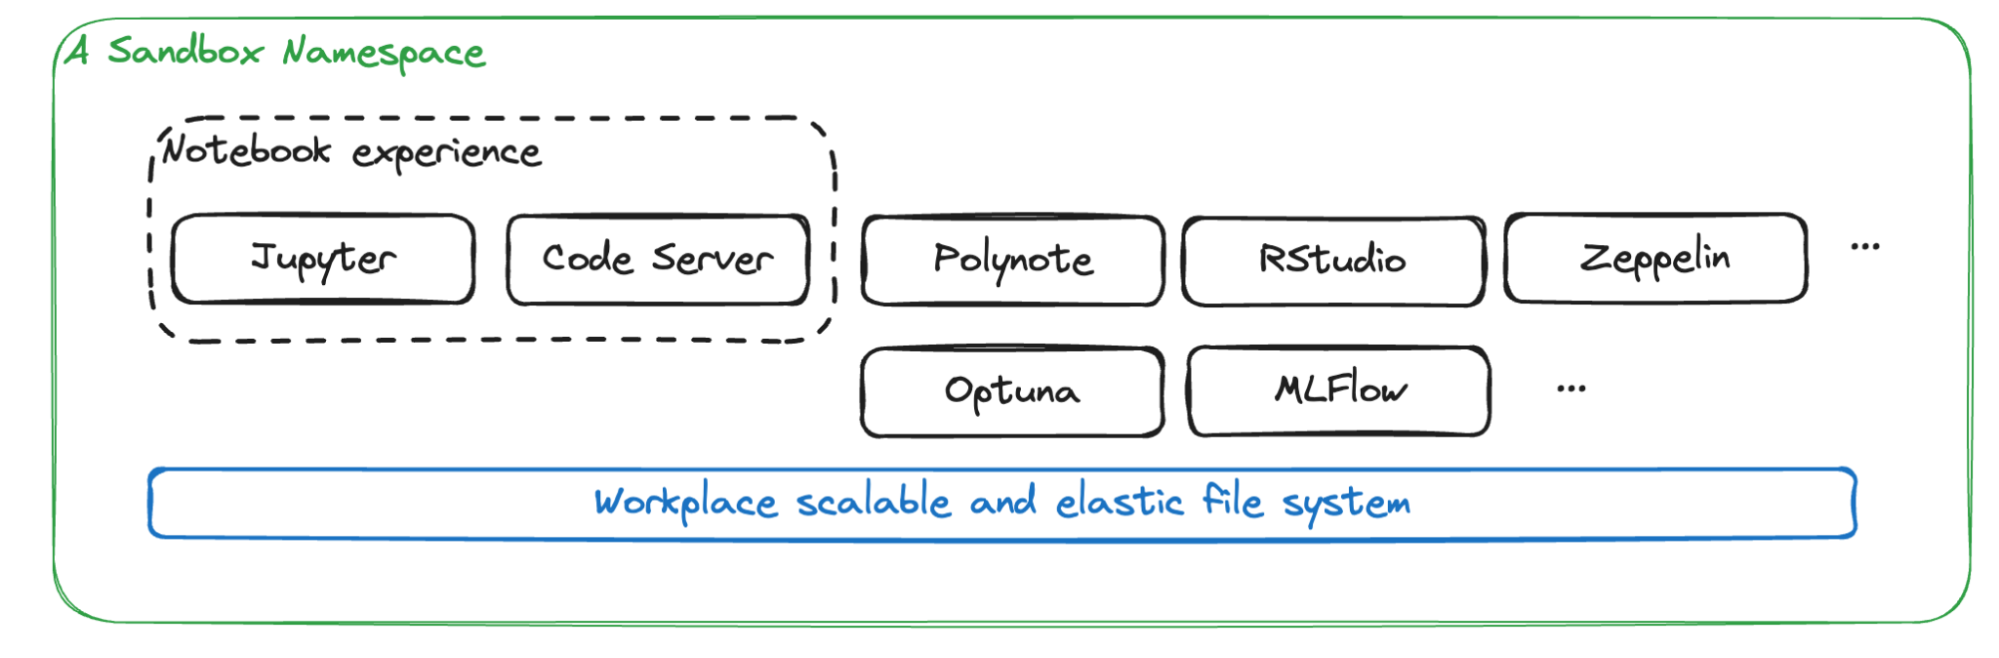
While Notebook is the most popular service on the platform, Chimera Sandbox offers much more than just notebook capabilities. It serves as a comprehensive namespace workspace equipped with a suite of ML/AI tools. Alongside notebooks, users can access essential ML tools such as Optuna for hyperparameter tuning, MLflow for experiment tracking, and other tools including Zeppelin, RStudio, Spark history, Polynote, and LabelStudio. All these services use a shared storage system, creating a tailored workspace for ML and AI tasks.

Figure 6. A Sandbox namespace with its out-of-the-box services.

Additionally, the Sandbox framework allows for the seamless integration of more services into personal workspaces. This high level of flexibility significantly enhances the capabilities of the Sandbox platform, making it an ideal environment for diverse ML and AI applications.

Cost attribution

For a multi-tenanted platform such as Chimera Sandbox, it is crucial to provide users information on how much they have spent with their experimentations. Cost showback and chargeback capabilities are of utmost importance for a platform on which users can launch Notebook services that use accelerated instances with GPUs. The platform provides cost attribution to individual users, so each user knows exactly how much they are spending on their experimentations and can make budget-conscious decisions. This transparency in cost attribution encourages responsible usage of resources and helps users manage their budgets effectively.

Growth and future plans

In essence, Chimera Sandbox is more than just a tool; it’s a catalyst for innovation and growth, empowering Grabbers to explore the frontiers of ML and AI. By providing an inclusive, flexible, and powerful platform, Chimera Sandbox is helping shape the future of Grab, making every Grabber not just ready but excited to contribute to the AI-driven transformation of our products and services.

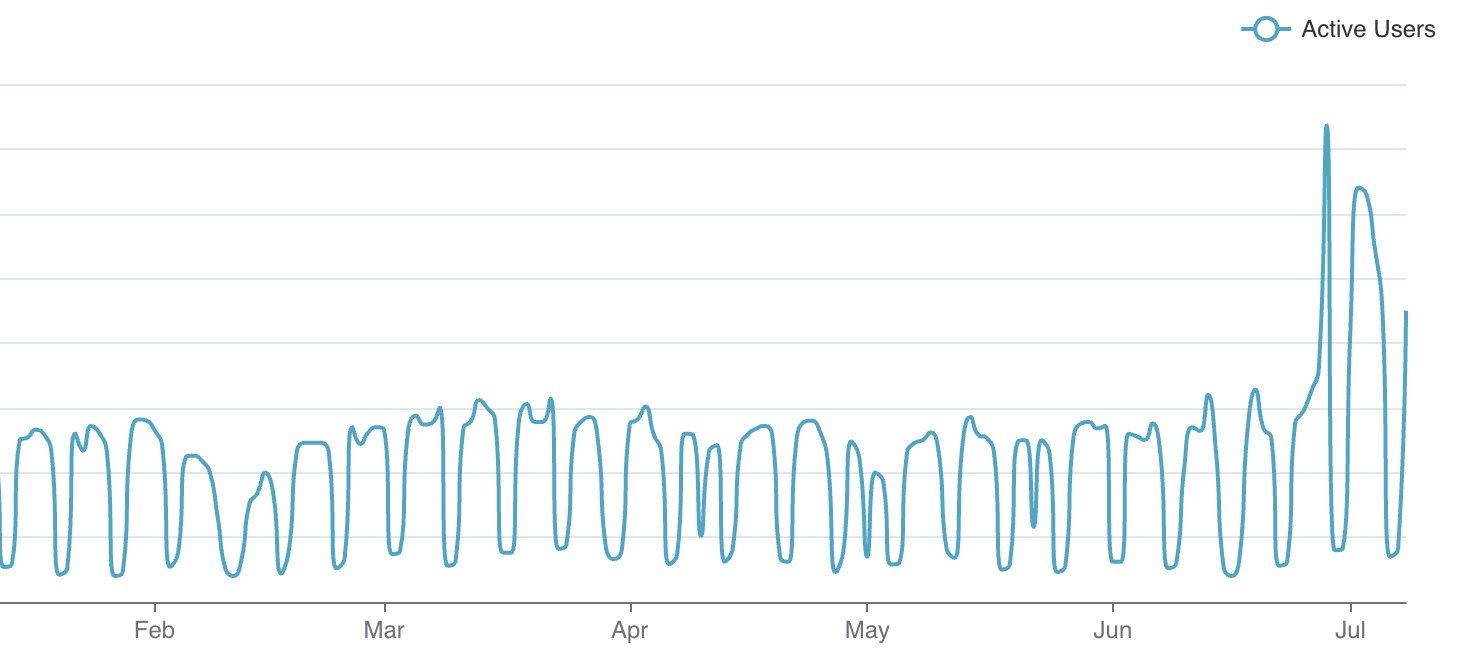
In July and August of this year, teams were given the opportunity to intensively learn and experiment with AI. Since then, we have observed hockey stick growth on the Chimera Sandbox platform. We are enabling massive experimentation across different teams at Grab to experiment and work on different GAI-powered applications.

Figure 7. Chimera Sandbox daily active users.

Our future plans include mechanisms for better notebook discovery, collaboration and usability, and the ability to enable users to schedule their notebooks right from Chimera Sandbox. These enhancements aim to improve the user experience and make the platform even more versatile and powerful.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

2024 ISO and CSA STAR certificates now available with three additional services

Post Syndicated from Atulsing Patil original https://aws.amazon.com/blogs/security/2024-iso-and-csa-star-certificates-now-available-with-three-additional-services/

Amazon Web Services (AWS) successfully completed an onboarding audit with no findings for ISO 9001:2015, 27001:2022, 27017:2015, 27018:2019, 27701:2019, 20000-1:2018, and 22301:2019, and Cloud Security Alliance (CSA) STAR Cloud Controls Matrix (CCM) v4.0. Ernst and Young CertifyPoint auditors conducted the audit and reissued the certificates on July 22, 2024. The objective of the audit was to assess the level of compliance with the requirements of the applicable international standards.

During the audit, we added the following three AWS services to the scope of the certification:

For a full list of AWS services that are certified under ISO and CSA Star, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the AWS Management Console through AWS Artifact.

If you have feedback about this post, submit comments in the Comments section below.

Atul Patil

Atulsing Patil
Atulsing is a Compliance Program Manager at AWS. He has 27 years of consulting experience in information technology and information security management. Atulsing holds a master of science in electronics degree and professional certifications such as CCSP, CISSP, CISM, CDPSE, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP.

Nimesh Ravas

Nimesh Ravasa
Nimesh is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Nimesh has 15 years of experience in information security and holds CISSP, CDPSE, CISA, PMP, CSX, AWS Solutions Architect – Associate, and AWS Security Specialty certifications.

Chinmaee Parulekar

Chinmaee Parulekar
Chinmaee is a Compliance Program Manager at AWS. She has 5 years of experience in information security. Chinmaee holds a master of science degree in management information systems and professional certifications such as CISA.

A malicious Pidgin plugin

Post Syndicated from corbet original https://lwn.net/Articles/987320/

The developers of the Pidgin chat program
have announced that
a malicious plugin had been listed on its third-party plugins list for over
one month. This plugin included a key logger and could capture
screenshots.

It went unnoticed at the time that the plugin was not providing any
source code and was only providing binaries for download. Going
forward, we will be requiring that all plugins that we link to have
an OSI Approved Open Source License and that some level of due
diligence has been done to verify that the plugin is safe for
users.

Intel Xeon 6 SoC for the Edge Hello Granite Rapids-D

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/intel-xeon-6-soc-for-the-edge-hello-granite-rapids-d/

In 2025 Intel Xeon D will get HUGE with the Intel Xeon 6 Granite Rapids-D platform. 100GbE, AMX, media encoders, 8-channel memory, and more

The post Intel Xeon 6 SoC for the Edge Hello Granite Rapids-D appeared first on ServeTheHome.

Tenstorrent Blackhole and Metalium For Standalone AI Processing

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/tenstorrent-blackhole-and-metalium-for-standalone-ai-processing/

At Hot Chips 2024, we got more information on the Tenstorrent Blackhole, a RISC-V based AI accelerator that uses 10x 400GbE for interconnect

The post Tenstorrent Blackhole and Metalium For Standalone AI Processing appeared first on ServeTheHome.

Copy and mask PII between Amazon RDS databases using visual ETL jobs in AWS Glue Studio

Post Syndicated from Monica Alcalde Angel original https://aws.amazon.com/blogs/big-data/copy-and-mask-pii-between-amazon-rds-databases-using-visual-etl-jobs-in-aws-glue-studio/

Moving and transforming data between databases is a common need for many organizations. Duplicating data from a production database to a lower or lateral environment and masking personally identifiable information (PII) to comply with regulations enables development, testing, and reporting without impacting critical systems or exposing sensitive customer data. However, manually anonymizing cloned information can be taxing for security and database teams.

You can use AWS Glue Studio to set up data replication and mask PII with no coding required. AWS Glue Studio visual editor provides a low-code graphic environment to build, run, and monitor extract, transform, and load (ETL) scripts. Behind the scenes, AWS Glue handles underlying resource provisioning, job monitoring, and retries. There’s no infrastructure to manage, so you can focus on rapidly building compliant data flows between key systems.

In this post, I’ll walk you through how to copy data from one Amazon Relational Database Service (Amazon RDS) for PostgreSQL database to another, while scrubbing PII along the way using AWS Glue. You will learn how to prepare a multi-account environment to access the databases from AWS Glue, and how to model an ETL data flow that automatically masks PII as part of the transfer process, so that no sensitive information will be copied to the target database in its original form. By the end, you’ll be able to rapidly build data movement pipelines between data sources and targets, that can hide PII in order to protect individual identities, without needing to write code.

Solution overview

The following diagram illustrates the solution architecture:
High-level architecture overview

The solution uses AWS Glue as an ETL engine to extract data from the source Amazon RDS database. Built-in data transformations then scrub columns containing PII using pre-defined masking functions. Finally, the AWS Glue ETL job inserts privacy-protected data into the target Amazon RDS database.

This solution employs multiple AWS accounts. Having multi-account environments is an AWS best practice to help isolate and manage your applications and data. The AWS Glue account shown in the diagram is a dedicated account that facilitates the creation and management of all necessary AWS Glue resources. This solution works across a broad array of connections that AWS Glue supports, so you can centralize the orchestration in one dedicated AWS account.

It is important to highlight the following notes about this solution:

  1. Following AWS best practices, the three AWS accounts discussed are part of an organization, but this is not mandatory for this solution to work.
  2. This solution is suitable for use cases that don’t require real-time replication and can run on a schedule or be initiated through events.

Walkthrough

To implement this solution, this guide walks you through the following steps:

  1. Enable connectivity from the AWS Glue account to the source and target accounts
  2. Create AWS Glue components for the ETL job
  3. Create and run the AWS Glue ETL job
  4. Verify results

Prerequisites

For this walkthrough, we’re using Amazon RDS for PostgreSQL 13.14-R1. Note that the solution will work with other versions and database engines that support the same JDBC driver versions as AWS Glue. See JDBC connections for further details.

To follow along with this post, you should have the following prerequisites:

  • Three AWS accounts as follows:
    1. Source account: Hosts the source Amazon RDS for PostgreSQL database. The database contains a table with sensitive information and resides within a private subnet. For future reference, record the associated virtual private cloud (VPC) ID, security group, and private subnets associated to the Amazon RDS database.
    2. Target account: Contains the target Amazon RDS for PostgreSQL database, with the same table structure as the source table, initially empty. The database resides within a private subnet. Similarly, write down the associated VPC ID, security group ID and private subnets.
    3. AWS Glue account: This dedicated account holds a VPC, a private subnet, and a security group. As mentioned in the AWS Glue documentation, the security group includes a self-referencing inbound rule for All TCP and TCP ports (0-65535) to allow AWS Glue to communicate with its components.

The following figure shows a self-referencing inbound rule needed on the AWS Glue account security group.
Self-referencing inbound rule needed on AWS Glue account’s security group

  • Make sure the three VPC CIDRs do not overlap with each other, as shown in the following table:
 VPC Private subnet
Source account   10.2.0.0/16 10.2.10.0/24
AWS Glue account   10.1.0.0/16 10.1.10.0/24
Target account   10.3.0.0/16 10.3.10.0/24

The following diagram illustrates the environment with all prerequisites:
Environment with all prerequisites

To streamline the process of setting up the prerequisites, you can follow the directions in the README file on this GitHub repository.

Database tables

For this example, both source and target databases contain a customer table with the exact same structure. The former is prepopulated with data as shown in the following figure:
Source database customer table pre-populated with data.

The AWS Glue ETL job you will create focuses on masking sensitive information within specific columns. These are last_name, email, phone_number, ssn and notes.

If you want to use the same table structure and data, the SQL statements are provided in the GitHub repository.

Step 1 – Enable connectivity from the AWS Glue account to the source and target accounts

When creating an AWS Glue ETL job, provide the AWS IAM role, VPC ID, subnet ID, and security groups needed for AWS Glue to access the JDBC databases. See AWS Glue: How it works for further details.

In our example, the role, groups, and other information are in the dedicated AWS Glue account. However, for AWS Glue to connect to the databases, you need to enable access to source and target databases from your AWS Glue account’s subnet and security group.

To enable access, first you inter-connect the VPCs. This can be done using VPC peering or AWS Transit Gateway. For this example, we use VPC peering. Alternatively, you can use an S3 bucket as an intermediary storage location. See Setting up network access to data stores for further details.

Follow these steps:

  1. Peer AWS Glue account VPC with the database VPCs
  2. Update the route tables
  3. Update the database security groups

Peer AWS Glue account VPC with database VPCs

Complete the following steps in the AWS VPC console:

  1. On the AWS Glue account, create two VPC peering connections as described in Create VPC peering connection, one for the source account VPC, and one for the target account VPC.
  2. On the source account, accept the VPC peering request. For instructions, see Accept VPC peering connection
  3. On the target account, accept the VPC peering request as well.
  4. On the AWS Glue account, enable DNS Settings on each peering connection. This allows AWS Glue to resolve the private IP address of your databases. For instructions, follow Enable DNS resolution for VPC peering connection.

After completing the preceding steps, the list of peering connections on the AWS Glue account should look like the following figure:
List of VPC peering connections on the AWS Glue account.Note that source and target account VPCs are not peered together. Connectivity between the two accounts isn’t needed.

Update subnet route tables

This step will enable traffic from the AWS Glue account VPC to the VPC subnets associate to the databases in the source and target accounts.

Complete the following steps in the AWS VPC console:

  1. On the AWS Glue account’s route table, for each VPC peering connection, add one route to each private subnet associated to the database. These routes enable AWS Glue to establish a connection to the databases and limit traffic from the AWS Glue account to only the subnets associated to the databases.
  2. On the source account’s route table of the private subnets associated to the database, add one route for the VPC peering with the AWS Glue account. This route will allow traffic back to the AWS Glue account.
  3. Repeat step 2 on the target account’s route table.

For instructions on how to update route tables, see Work with route tables.

Update database security groups

This step is required to allow traffic from the AWS Glue account’s security group to the source and target security groups associated to the databases.

For instructions on how to update security groups, see Work with security groups.

Complete the following steps in the AWS VPC console:

  1. On the source account’s database security group, add an inbound rule with Type PostgreSQL and Source, the AWS Glue account security group.
  2. Repeat step 1 from the target account’s database security group.

The following diagram shows the environment with connectivity enabled from the AWS Glue account to the source and target accounts:Environment with connectivity across accounts enabled.

Step 2 – Create AWS Glue components for the ETL job

The next task is to create the AWS Glue components to synchronize the source and target database schemas with the AWS Glue Data Catalog.

Follow these steps:

  1. Create an AWS Glue Connection for each Amazon RDS database.
  2. Create AWS Glue Crawlers to populate the Data Catalog.
  3. Run the crawlers.

Create AWS Glue connections

Connections enable AWS Glue to access your databases. The main benefit of creating AWS Glue connections is that connections save time by not making you have to specify all connection details every time you create a job. You can then reuse connections when creating jobs in AWS Glue Studio without having to manually enter connection details each time. This makes the job creation process more consistent and faster.

Complete these steps on the AWS Glue account:

  1. On the AWS Glue console, choose the Data connections link on the navigation pane.
  2. Choose Create connection and follow the instructions in the Create connection wizard:
    1. In Choose data source, choose JDBC as data source.
    2. In Configure connection:
      • For JDBC URL, enter the JDBC URL for the source database. For PostgreSQL, the syntax is:
        jdbc:postgresql://database-endpoint:5432/database-name

        You can find the database-endpoint on the Amazon RDS console on the source account.

      • Expand Network options. For VPC, Subnet and Security group, select the ones in the centralized AWS Glue account, as shown in the following figure:
        Network settings (VPC, subnet and security group) for the AWS Glue connection.
    3. In Set Properties, for Name enter Source DB connection-Postgresql.
  3. Repeat steps 1 and 2 to create the connection to the target Amazon RDS database. Name the connection Target DB connection-Postgresql.

Now you have two connections, one for each Amazon RDS database.

Create AWS Glue crawlers

AWS Glue crawlers allow you to automate data discovery and cataloging from data sources and targets. Crawlers explore data stores and auto-generate metadata to populate the Data Catalog, registering discovered tables in the Data Catalog. This helps you to discover and work with the data to build ETL jobs.

To create a crawler for each Amazon RDS database, complete the following steps on the AWS Glue account:

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Choose Create crawler and follow the instructions in the Add crawler wizard:
    1. In Set crawler properties, for Name enter Source PostgreSQL database crawler.
    2. In Chose data sources and classifiers, choose Not yet.
    3. In Add data source, for Data source choose JDBC, as shown in the following figure:
      AWS Glue crawler JDBC data source settings.
    4. For Connection, choose Source DB Connection - Postgresql.
    5. For Include path, enter the path of your database including the schema. For our example, the path is sourcedb/cx/% where sourcedb is the name of the database, and cx the schema with the customer table.
    6. In Configure security settings, choose the AWS IAM service role created a part of the prerequisites.
    7. In Set output and scheduling, since we don’t have a database yet in the Data Catalog to store the source database metadata, choose Add database and create a database named sourcedb-postgresql.
  3. Repeat steps 1 and 2 to create a crawler for the target database:
    1. In Set crawler properties, for Name enter Target PostgreSQL database crawler.
    2. In Add data source, for Connection, choose Target DB Connection-Postgresql, and for Include path enter targetdb/cx/%.
    3. In Add database, for Name enter targetdb-postgresql.

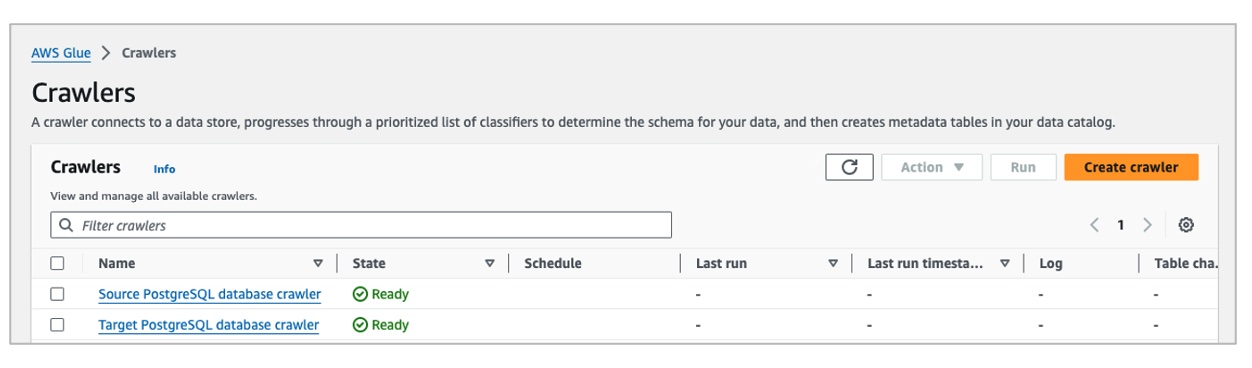
Now you have two crawlers, one for each Amazon RDS database, as shown in the following figure:List of crawlers created.

Run the crawlers

Next, run the crawlers. When you run a crawler, the crawler connects to the designated data store and automatically populates the Data Catalog with metadata table definitions (columns, data types, partitions, and so on). This saves time over manually defining schemas.

From the Crawlers list, select both Source PostgreSQL database crawler and Target PostgreSQL database crawler, and choose Run.

When finished, each crawler creates a table in the Data Catalog. These tables are the metadata representation of the customer tables.

You now have all the resources to start creating AWS Glue ETL jobs!

Step 3 – Create and run the AWS Glue ETL Job

The proposed ETL job runs four tasks:

  1. Source data extraction – Establishes a connection to the Amazon RDS source database and extracts the data to replicate.
  2. PII detection and scrubbing.
  3. Data transformation – Adjusts and removes unnecessary fields.
  4. Target data loading – Establishes a connection to the target Amazon RDS database and inserts data with masked PII.

Let’s jump into AWS Glue Studio to create the AWS Glue ETL job.

  1. Sign in to the AWS Glue console with your AWS Glue account.
  2. Choose ETL jobs in the navigation pane.
  3. Choose Visual ETL as shown in the following figure:

Entry point to AWS Glue Studio visual interface

Task 1 – Source data extraction

Add a node to connect to the Amazon RDS source database:

  1. Choose AWS Glue Data Catalog from the Sources. This adds a data source node to the canvas.
  2. On the Data source properties panel, select sourcedb-postgresql database and source_cx_customer table from the Data Catalog as shown in the following figure:

Highlights AWS Glue Data Catalog data source node on the left hand side, and the data source node properties on the right hand side.

Task 2 – PII detection and scrubbing

To detect and mask PII, select Detect Sensitive Data node from the Transforms tab.

Let’s take a deeper look into the Transform options on the properties panel for the Detect Sensitive Data node:

  1. First, you can choose how you want the data to be scanned. You can select Find sensitive data in each row or Find columns that contain sensitive data as shown in the following figure. Choosing the former scans all rows for comprehensive PII identification, while the latter scans a sample for PII location at lower cost.

Find sensitive data in each row option selected to detect sensitive data.

Selecting Find sensitive data in each row allows you to specify fine-grained action overrides. If you know your data, with fine-grained actions you can exclude certain columns from detection. You can also customize the entities to detect for every column in your dataset and skip entities that you know aren’t in specific columns. This allows your jobs to be more performant by eliminating unnecessary detection calls for those entities and perform actions unique to each column and entity combination.

In our example, we know our data and we want to apply fine-grained actions to specific columns, so let’s select Find sensitive data in each row. We’ll explore fine-grained actions further below.

  1. Next, you select the types of sensitive information to detect. Take some time to explore the three different options.

In our example, again because we know the data, let’s select Select specific patterns. For Selected patterns, choose Person’s name, Email Address, Credit Card, Social Security Number (SSN) and US Phone as shown in the following figure. Note that some patterns, such as SSNs, apply specifically to the United States and might not detect PII data for other countries. But there are available categories applicable to other countries, and you can also use regular expressions in AWS Glue Studio to create detection entities to help meet your needs.

Patterns selected for detecting PII data

  1. Next, select the level of detection sensitivity. Leave the default value (High).
  2. Next, choose the global action to take on detected entities. Select REDACT and enter **** as the Redaction Text.
  3. Next, you can specify fine-grained actions (overrides). Overrides are optional, but in our example, we want to exclude certain columns from detection, scan certain PII entity types on specific columns only, and specify different redaction text settings for different entity types.

Choose Add to specify the fine-grained action for each entity as shown in the following figure:List of fine-grained actions created. The screenshot includes an arrow pointing to the Add button.

Task 3 – Data transformation

When the Detect Sensitive Data node runs, it converts the id column to string type and it adds a column named DetectedEntities with PII detection metadata to the output. We don’t need to store such metadata information in the target table, and we need to convert the id column back to integer, so let’s add a Change Schema transform node to the ETL job, as shown in the following figure. This will make these changes for us.

Note: You must select the DetectedEntities Drop checkbox for the transform node to drop the added field.

Task 4 – Target data loading

The last task for the ETL job is to establish a connection to the target database and insert the data with PII masked:

  1. Choose AWS Glue Data Catalog from the Targets. This adds a data target node to the canvas.
  2. On the Data target properties panel, choose targetdb-postgresql and target_cx_customer, as shown in the following figure.

Target node added to the ETL Job

Save and run the ETL job

  1. From the Job details tab, for Name, enter ETL - Replicate customer data.
  2. For IAM Role, choose the AWS Glue role created as part of the prerequisites.
  3. Choose Save, then choose Run.

Monitor the job until it successfully finishes from Job run monitoring on the navigation pane.

Step 4 – Verify the results

Connect to the Amazon RDS target database and verify that the replicated rows contain the scrubbed PII data, confirming sensitive information was masked properly in transit between databases as shown in the following figure:Target customer database table with PII data masked.

And that’s it! With AWS Glue Studio, you can create ETL jobs to copy data between databases and transform it along the way without any coding. Try other types of sensitive information for securing your sensitive data during replication. Also try adding and combining multiple and heterogenous data sources and targets.

Clean up

To clean up the resources created:

  1. Delete the AWS Glue ETL job, crawlers, Data Catalog databases, and connections.
  2. Delete the VPC peering connections.
  3. Delete the routes added to the route tables, and inbound rules added to the security groups on the three AWS accounts.
  4. On the AWS Glue account, delete associated Amazon S3 objects. These are in the S3 bucket with aws-glue-assets-account_id-region in its name, where account-id is your AWS Glue account ID, and region is the AWS Region you used.
  5. Delete the Amazon RDS databases you created if you no longer need them. If you used the GitHub repository, then delete the AWS CloudFormation stacks.

Conclusion

In this post, you learned how to use AWS Glue Studio to build an ETL job that copies data from one Amazon RDS database to another and automatically detects PII data and masks the data in-flight, without writing code.

By using AWS Glue for database replication, organizations can eliminate manual processes to find hidden PII and bespoke scripting to transform it by building centralized, visible data sanitization pipelines. This improves security and compliance, and speeds time-to-market for test or analytics data provisioning.


About the Author

Monica Alcalde Angel is a Senior Solutions Architect in the Financial Services, Fintech team at AWS. She works with Blockchain and Crypto AWS customers, helping them accelerate their time to value when using AWS. She lives in New York City, and outside of work, she is passionate about traveling.
AWS Weekly Roundup: S3 Conditional writes, AWS Lambda, JAWS Pankration, and more (August 26, 2024)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-s3-conditional-writes-aws-lambda-jaws-pankration-and-more-august-26-2024/

The AWS User Group Japan (JAWS-UG) hosted JAWS PANKRATION 2024 themed ‘No Border’. This is a 24-hour online event where AWS Heroes, AWS Community Builders, AWS User Group leaders, and others from around the world discuss topics ranging from cultural discussions to technical talks. One of the speakers at this event, Kevin Tuei, an AWS Community Builder based in Kenya, highlighted the importance of building in public and sharing your knowledge with others, a very fitting talk for this kind of event.

Last week’s launches
Here are some launches that got my attention during the previous week.

Amazon S3 now supports conditional writes – We’ve added support for conditional writes in Amazon S3 which check for existence of an object before creating it. With this feature, you can now simplify how distributed applications with multiple clients concurrently update data in parallel across shared datasets. Each client can conditionally write objects, making sure that it does not overwrite any objects already written by another client.

AWS Lambda introduces recursive loop detection APIs – With the recursive loop detection APIs you can now set recursive loop detection configuration on individual AWS Lambda functions. This allows you to turn off recursive loop detection on functions that intentionally use recursive patterns, avoiding disruption of these workloads. Using these APIs, you can avoid disruption to any intentionally recursive workflows as Lambda expands support of recursive loop detection to other AWS services. Configure recursive loop detection for Lambda functions through the Lambda Console, the AWS command line interface (CLI), or Infrastructure as Code tools like AWS CloudFormation, AWS Serverless Application Model (AWS SAM), or AWS Cloud Development Kit (CDK). This new configuration option is supported in AWS SAM CLI version 1.123.0 and CDK v2.153.0.

General availability of Amazon Bedrock batch inference API – You can now use Amazon Bedrock to process prompts in batch to get responses for model evaluation, experimentation, and offline processing. Using the batch API makes it more efficient to run inference with foundation models (FMs). It also allows you to aggregate responses and analyze them in batches. To get started, visit Run batch inference.

Other AWS news
Launched in July 2024, AWS GenAI Lofts is a global tour designed to foster innovation and community in the evolving landscape of generative artificial intelligence (AI) technology. The lofts bring collaborative pop-up spaces to key AI hotspots around the world, offering developers, startups, and AI enthusiasts a platform to learn, build, and connect. The events are ongoing. Find a location near you and be sure to attend soon.

Upcoming AWS events
AWS Summits – These are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Whether you’re in the Americas, Asia Pacific & Japan, or EMEA region, learn more about future AWS Summit events happening in your area. On a personal note, I look forward to being one of the keynote speakers at the AWS Summit Johannesburg happening this Thursday. Registrations are still open and I look forward to seeing you there if you’ll be attending.

AWS Community Days – Join an AWS Community Day event just like the one I mentioned at the beginning of this post to participate in technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from your area. If you’re in New York, there’s an event happening in your area this week.

You can browse all upcoming in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Veliswa

Summer 2024 SOC report now available with 177 services in scope

Post Syndicated from Brownell Combs original https://aws.amazon.com/blogs/security/summer-2024-soc-report-now-available-with-177-services-in-scope/

We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Summer 2024 System and Organization Controls (SOC) 1 report is now available. The report covers 177 services over the 12-month period of July 1, 2023–June 30, 2024, so that customers have a full year of assurance with the report. This report demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers.

Going forward, we will issue SOC reports covering a 12-month period each quarter as follows:

Report Period covered
Spring SOC 1, 2, and 3 April 1–March 31
Summer SOC 1 July 1–June 30
Fall SOC 1, 2, and 3 October 1–September 30
Winter SOC 1 January 1–December 31

Customers can download the Summer 2024 SOC report through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If you have questions or feedback about SOC compliance, reach out to your AWS account team.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Brownell Combs
Brownell Combs

Brownell is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Brownell holds a master of science degree in computer science from University of Virginia and a bachelor of science degree in computer science from Centre College. He has over 20 years of experience in IT risk management and CISSP, CISA, CRISC, and GIAC GCLD certifications.
Paul Hong
Paul Hong

Paul is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS, and has 10 years of experience in security assurance. Paul holds CISSP, CEH, and CPA certifications. He has a master’s degree in accounting information systems and a bachelor’s degree in business administration from James Madison University, Virginia.
Tushar Jain
Tushar Jain

Tushar is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS. Tushar holds a master of business administration from Indian Institute of Management Shillong, and a bachelor of technology in electronics and telecommunication engineering from Marathwada University. He has over 12 years of experience in information security and holds CCSK and CSXF certifications.
Michael Murphy
Michael Murphy

Michael is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Michael has 12 years of experience in information security. He holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.
Nathan Samuel
Nathan Samuel

Nathan is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Nathan has a bachelor of commerce degree from the University of the Witwatersrand, South Africa, and has over 21 years of experience in security assurance. He holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.
ryan wilks
Ryan Wilks

Ryan is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Ryan has 13 years of experience in information security. He has a bachelor of arts degree from Rutgers University and holds ITIL, CISM, and CISA certifications.

The collective thoughts of the interwebz