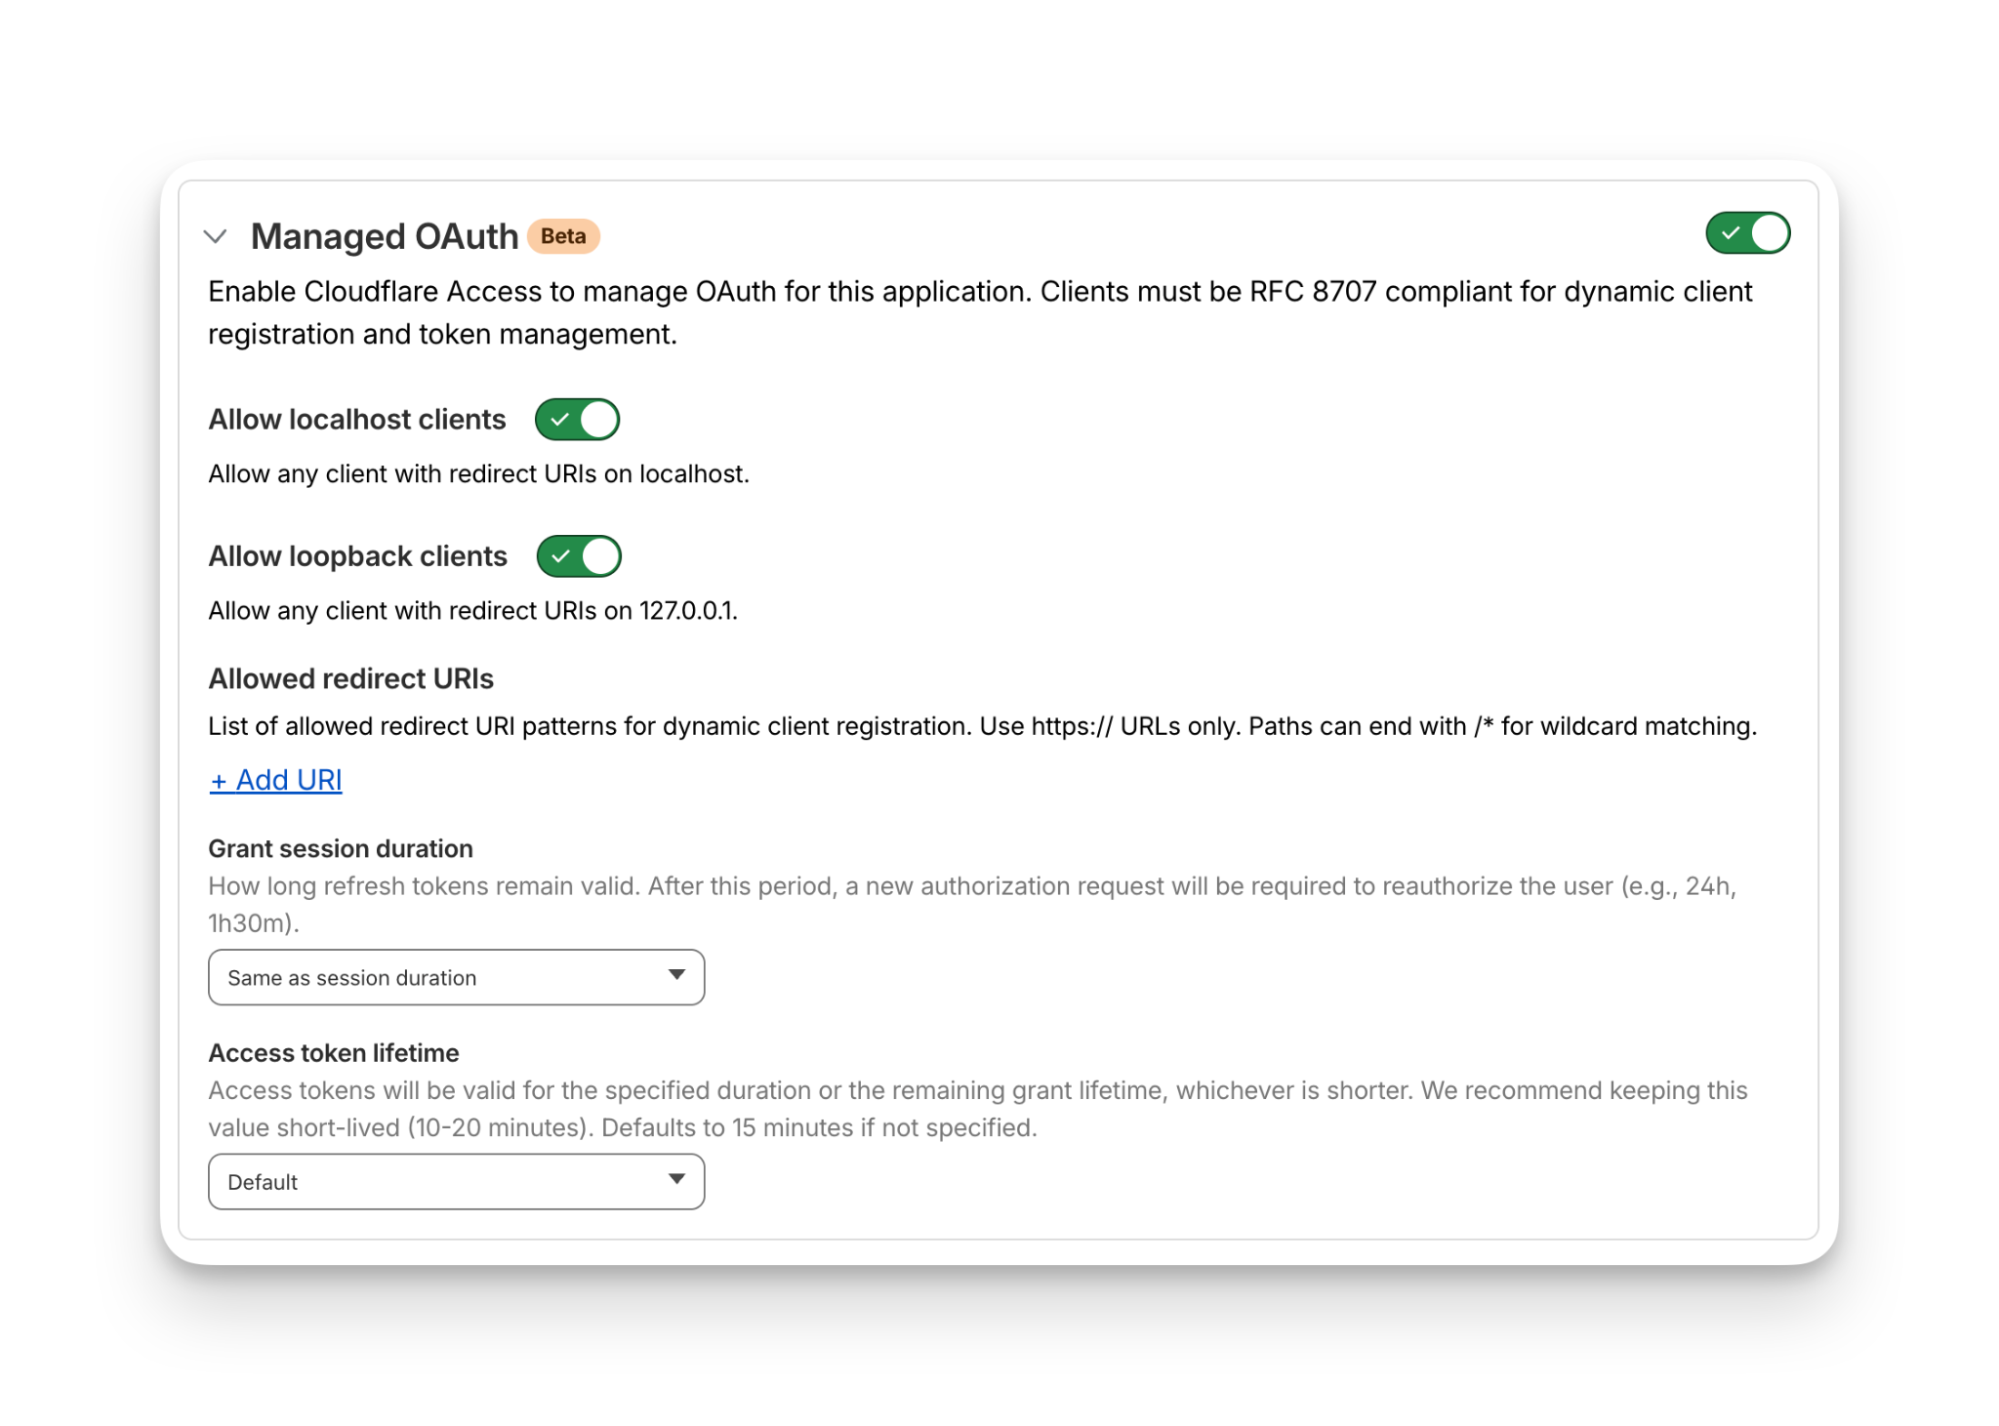
Tag Archives: Agents

AI Search: the search primitive for your agents

Post Syndicated from Anni Wang original https://blog.cloudflare.com/ai-search-agent-primitive/

Every agent needs search: Coding agents search millions of files across repos. Support agents search customer tickets and internal docs. Even an agent’s memory, its ability to recall past interactions, is fundamentally a search problem. The use cases are different, but the underlying problem is the same: get the right information to the model at the right time.

If you’re building search yourself, you need a vector index, an indexing pipeline that parses and chunks your documents, and something to keep the index up to date when your data changes. If you also need keyword search, that’s a separate index and fusion logic on top. And if each of your agents needs its own searchable context, you’re setting all of that up per agent. 

AI Search (formerly AutoRAG) is the plug-and-play search primitive you need. You can dynamically create instances, give it your data, and search — from a Worker, the Agents SDK, or Wrangler CLI. Here’s what we’re shipping:

  • Hybrid search. Enable both semantic and keyword matching in the same query. Vector search and BM25 run in parallel and results are fused. (The search on our blog is now powered by AI Search. Try the magnifying glass icon to the top right.)

  • Built-in storage and index. New instances come with their own storage and vector index. Upload files directly to an instance via API and they’re indexed. No R2 buckets to set up, no external data sources to connect first. The new ai_search_namespaces binding lets you create and delete instances at runtime from your Worker, so you can spin up one per agent, per customer, or per language without redeployment.

You can now also attach metadata to documents and use it to boost rankings at query time, and query across multiple instances in a single call. 

Now, let’s look at what this means in practice.

In action: Customer Support Agent

Let’s walk through a support agent that searches for two kinds of knowledge: shared product docs, and per-customer history like past resolutions. The product docs are too large to fit in a context window, and each customer’s history grows with every resolved issue, so the agent needs retrieval to find what’s relevant.

Here’s what that looks like with AI Search and the Agents SDK. Start by scaffolding a project:

npm create cloudflare@latest -- --template cloudflare/agents-starter

First, bind an AI Search namespace to your Worker:

// wrangler.jsonc 
{
  "ai_search_namespaces": [
    { "binding": "SUPPORT_KB", "namespace": "support" }
  ],
  "ai": { "binding": "AI" },
  "durable_objects": {
    "bindings": [
      { "name": "SupportAgent", "class_name": "SupportAgent" }
    ]
  }
}

Let’s say your shared product documentation lives in an R2 bucket called product-doc. You can create a one-off AI Search instance (named product-knowledge) backed by the bucket on the Cloudflare Dashboard within the support namespace:


That’s your shared knowledge base, the docs every agent can reference.

When a customer comes back with a new issue, knowing what’s already been tried saves everyone time. You can track this by creating an AI Search instance per customer. After each resolved issue, the agent saves a summary of what went wrong and how it was fixed. Over time, this builds up a searchable log of past resolutions. You can create instances dynamically using the namespace binding:

// create a per-customer instance when they first show up 
await env.SUPPORT_KB.create({
  id: `customer-${customerId}`,
  index_method:{ keyword: true, vector: true }
});

Each instance gets its own built-in storage and vector index — powered by R2 and Vectorize. The instance starts empty and accumulates context over time. Next time the customer comes back, all of it is searchable.

Here’s what the namespace looks like after a few customers:

namespace: "support"
├── product-knowledge     (R2 as source, shared across all agents)
├── customer-abc123       (managed storage, per-customer)
├── customer-def456       (managed storage, per-customer)
└── customer-ghi789       (managed storage, per-customer)

Now the agent itself. It extends AIChatAgent from the Agents SDK and defines two tools. We’re using Kimi K2.5 as the LLM via Workers AI. The model decides when to call the tools based on the conversation:

import { AIChatAgent, type OnChatMessageOptions } from "@cloudflare/ai-chat";
import { createWorkersAI } from "workers-ai-provider";
import { streamText, convertToModelMessages, tool, stepCountIs } from "ai";
import { routeAgentRequest } from "agents";
import { z } from "zod";

export class SupportAgent extends AIChatAgent<Env> {
  async onChatMessage(_onFinish: unknown, options?: OnChatMessageOptions) {
    // the client passes customerId in the request body
    // via the Agent SDK's sendMessage({ body: { customerId } })
    const customerId = options?.body?.customerId;

    // create a per-customer instance when they first show up.
    // each instance gets its own storage and vector index.
    if (customerId) {
      try {
        await this.env.SUPPORT_KB.create({
          id: `customer-${customerId}`,
          index_method: { keyword: true, vector: true }
        });
      } catch {
        // instance already exists
      }
    }

    const workersai = createWorkersAI({ binding: this.env.AI });

    const result = streamText({
      model: workersai("@cf/moonshotai/kimi-k2.5"),
      system: `You are a support agent. Use search_knowledge_base
        to find relevant docs before answering. Search results
        include both product docs and this customer's past
        resolutions — use them to avoid repeating failed fixes
        and to recognize recurring issues. When the issue is
        resolved, call save_resolution before responding.`,
      // this.messages is the full conversation history, automatically
      // persisted by AIChatAgent across reconnects
      messages: await convertToModelMessages(this.messages),
      tools: {
        // tool 1: search across shared product docs AND this
        // customer's past resolutions in a single call
        search_knowledge_base: tool({
          description: "Search product docs and customer history",
          inputSchema: z.object({
            query: z.string().describe("The search query"),
          }),
          execute: async ({ query }) => {
            // always search product docs;
            // include customer history if available
            const instances = ["product-knowledge"];
            if (customerId) {
              instances.push(`customer-${customerId}`);
            }
            return await this.env.SUPPORT_KB.search({
              query: query,
              ai_search_options: {
                // surface recent docs over older ones
                boost_by: [
                  { field: "timestamp", direction: "desc" }
                ],
                // search across both instances at once
                instance_ids: instances
              }
            });
          }
        }),

        // tool 2: after resolving an issue, the agent saves a
        // summary so future agents have full context
        save_resolution: tool({
          description:
            "Save a resolution summary after solving a customer's issue",
          inputSchema: z.object({
            filename: z.string().describe(
              "Short descriptive filename, e.g. 'billing-fix.md'"
            ),
            content: z.string().describe(
              "What the problem was, what caused it, and how it was resolved"
            ),
          }),
          execute: async ({ filename, content }) => {
            if (!customerId) return { error: "No customer ID" };
            const instance = this.env.SUPPORT_KB.get(
              `customer-${customerId}`
            );
            // uploadAndPoll waits until indexing is complete,
            // so the resolution is searchable before the next query
            const item = await instance.items.uploadAndPoll(
              filename, content
            );
            return { saved: true, filename, status: item.status };
          }
        }),
      },
      // cap agentic tool-use loops at 10 steps
      stopWhen: stepCountIs(10),
      abortSignal: options?.abortSignal,
    });

    return result.toUIMessageStreamResponse();
  }
}

// route requests to the SupportAgent durable object
export default {
  async fetch(request: Request, env: Env) {
    return (
      (await routeAgentRequest(request, env)) ||
      new Response("Not found", { status: 404 })
    );
  }
} satisfies ExportedHandler<Env>;

With this, the model decides when to search and when to save. When it searches, it queries product-knowledge and this customer’s past resolutions together. When the issue is resolved, it saves a summary that’s immediately searchable in future conversations. 

How AI Search finds what you’re looking for

Under the hood, AI Search runs a multi-step retrieval pipeline, in which every step is configurable.

Hybrid Search: search that understands intent and matches terms

Until now, AI Search only offered vector search. Vector search is great at understanding intent, but it can lose specifics. In a query “ERR_CONNECTION_REFUSED timeout,” the embedding captures the broad concept of connection failures. But the user isn’t looking for general networking docs. They’re looking for the specific document that mentions “ERR_CONNECTION_REFUSED”. Vector search might return results about troubleshooting without ever surfacing the page that contains that exact error string. 

Keyword search fills that gap. AI Search now supports BM25, one of the most widely used retrieval scoring functions. BM25 scores documents by how often your query terms appear, how rare those terms are across the entire corpus, and how long the document is. It rewards matches on specific terms, penalizes common filler words, and normalizes for document length. When you search “ERR_CONNECTION_REFUSED timeout”, BM25 finds documents that actually contain “ERR_CONNECTION_REFUSED” as a term. However, BM25 may miss a page about “troubleshooting network connections” even though it may be describing the same problem. That’s where vector search shines, and why you need both.

When you enable hybrid search, it runs vector and BM25 in parallel, fuses the results, and optionally reranks them:
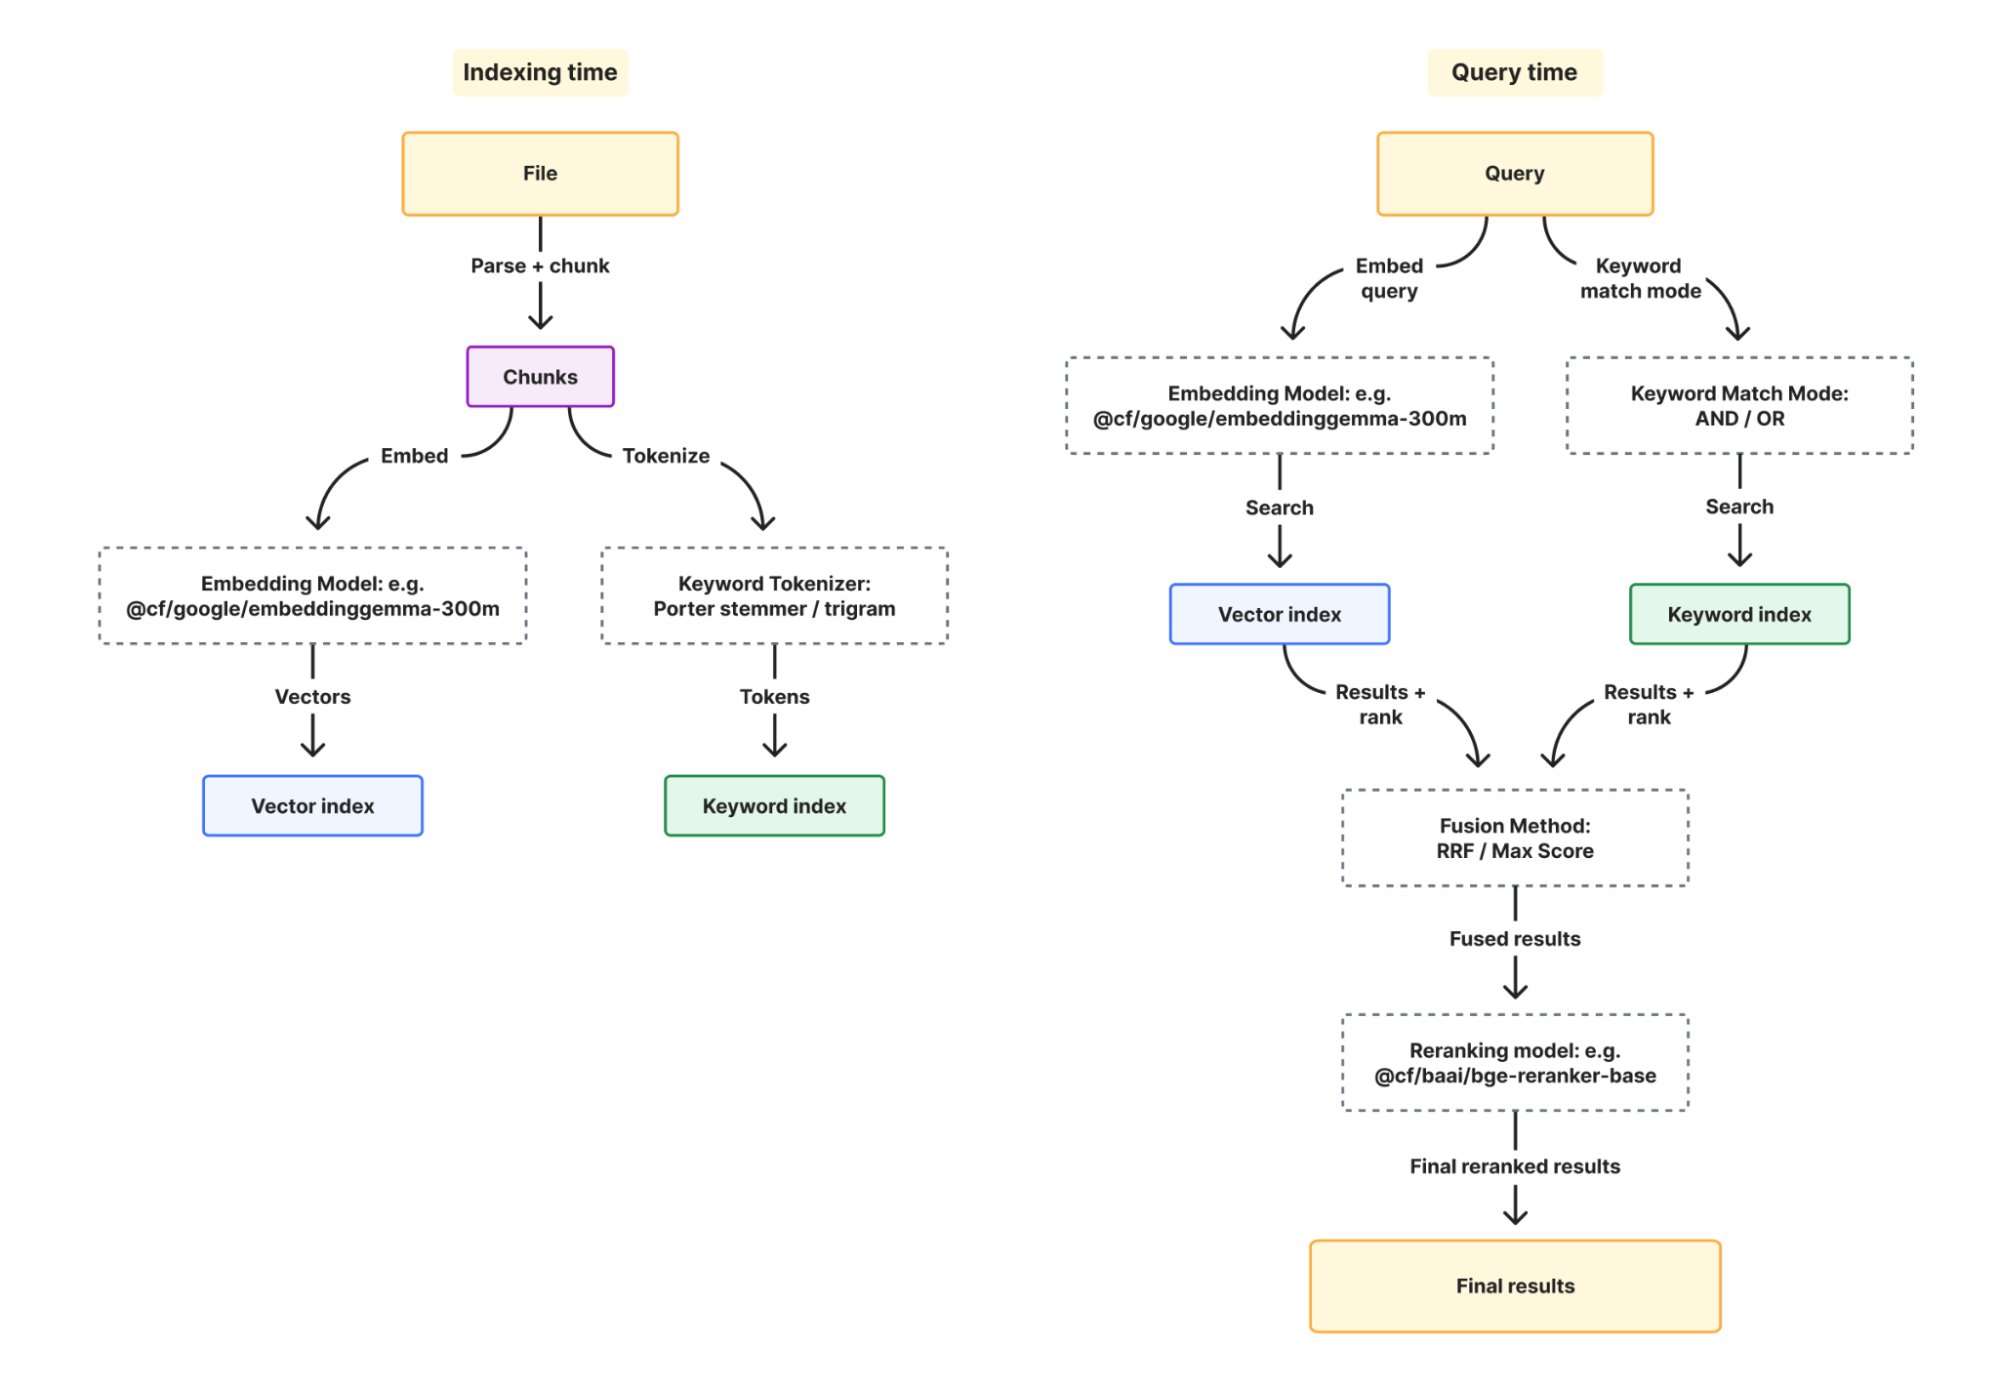

Let’s take a look at the new configurations for BM25, and how they come together.

  1. Tokenizer controls how your documents are broken into matchable terms at index time. Porter stemmer (option: porter) stems words so “running” matches “run.” Trigram (option: trigram) matches character substrings so “conf” matches “configuration.” You can use porter for natural language content like docs, and trigram for code where partial matches matter.

  2. Keyword match mode controls which documents are candidates for BM25 scoring at query time. AND requires all query terms to appear in a document, OR includes anything with at least one match.

  3. Fusion controls how vector and keyword results are combined into the final list of results during query time. Reciprocal rank fusion (option: rrf) merges by rank position rather than score, which avoids comparing two incompatible scoring scales, whereas max fusion (option: max) takes the higher score.

  4. (Optional) Reranking adds a cross-encoder pass that re-scores results by evaluating the query and document together as a pair. It can help catch cases where a result has the right terms but isn’t answering the question. 

Every option has a sane default when omitted. You have the flexibility to configure what matters whenever you create a new instance:

const instance = await env.AI_SEARCH.create({
  id: "my-instance",
  index_method: { keyword: true, vector: true },
  indexing_options: {
    keyword_tokenizer: "porter"
  },
  retrieval_options: {
    keyword_match_mode: "or"
  },
  fusion_method: "rrf",
  reranking: true,
  reranking_model: "@cf/baai/bge-reranker-base"
});

Boost relevance: surface what matters

Retrieval gets you relevant results, but relevance alone isn’t always enough. For example, in a news search, an article from last week and an article from three years ago might both be semantically relevant to “election results,” but most users probably want the recent one. Boosting lets you layer business logic on top of retrieval by nudging rankings based on document metadata.

You can boost on timestamp (built in on every item) or any custom metadata field you define.

// boost high priority docs
const results = await instance.search({
  query: "deployment guide",
  ai_search_options: {
    boost_by: [
      { field: "timestamp", direction: "desc" }
    ]
  }
});

Cross-instance search: query across boundaries

In the support agent example, product documentation and customer resolution history live in separate instances by design. But when the agent is answering a question, it needs context from both places at once. Without cross-instance search, you’d make two separate calls and merge the results yourself.

The namespace binding exposes a search() method that handles this for you. Pass an array of instance names and get one ranked list back:

const results = await env.SUPPORT_KB.search({
  query: "billing error",
  ai_search_options: {
    instance_ids: ["product-knowledge", "customer-abc123"]
  }
});

Results are merged and ranked across instances. The agent doesn’t need to know or care that shared docs and customer resolution history live in separate places. 

How AI Search instances work

So far we’ve covered how AI Search finds the right results. Now let’s look at how you can create and manage your search instances.

If you used AI Search before this release, you know the setup: create an R2 bucket, link it to an AI Search instance, AI search generates a service API token for you, and you manage the Vectorize index that gets provisioned on your account. Uploading an object requires you to write to R2 and then wait for a sync job to run to have the object indexed.

New instances created now work differently. When you call create(), the instance comes with its own storage and vector index built-in. You can upload a file, the file is sent to index immediately, and you can poll for indexing status all with one uploadAndpoll() API. Once completed, you can search the instance immediately, and there are no external dependencies to wire together.

const instance = env.AI_SEARCH.get("my-instance");

// upload and wait for indexing to complete
const item = await instance.items.uploadAndPoll("faq.md", content, {
  metadata: { category: "onboarding" }
});
console.log(item.status); // "completed"

// immediately search after indexing is completed
const results = await instance.search({
  // alternative way to pass in users' query other than using parameter query 
  messages: [{ role: "user", content: "onboarding guide" }],
});

Each instance can also connect to one external data source (an R2 bucket or a website) and run on a sync schedule. It can exist alongside the provided built-in storage. In the support agent example, product-knowledge is backed by an R2 bucket for shared documentation, while each customer’s instance uses built-in storage for context uploaded on the fly.

Namespaces: create search instances at runtime

The ai_search_namespaces is a new binding you can leverage to dynamically create search instances at runtime. It replaces the previous env.AI.autorag() API, which accessed AI Search through the AI binding. The old bindings will continue to work using Workers compatibility dates.

// wrangler.jsonc 
{
  "ai_search_namespaces": [
    { "binding": "AI_SEARCH", "namespace": "example" },
  ]
}

The namespace binding gives you APIs like create(), delete(), list(), and search() at the namespace level. If you’re creating instances dynamically (e.g. per agent, per customer, per tenant), this is the binding to use.

// create an instance 
const instance = await env.AI_SEARCH.create({
  id: "my-instance"
});

// delete an instance and all its indexed data
await env.AI_SEARCH.delete("old-instance");

Pricing for new instances

New instances created as of today will get built-in storage and a vector index automatically. 

These instances are free to use while AI Search is in open beta with the limits listed below. When using the website as a data source, website crawling using Browser Run (formerly Browser Rendering) is also now a built-in service, meaning that you won’t be billed for it separately. After beta, the goal is to provide unified pricing for AI Search as a single service, rather than billing separately for each underlying component. Workers AI and AI Gateway usage will continue to be billed separately.

We’ll give at least 30 days notice and communicate pricing details before any billing begins.

Limit

Workers Free

Workers Paid

AI Search instances per account

100

5,000

Files per instance

100,000

1M or 500K for hybrid search

Max file size

4MB

4MB

Queries per month

20,000

Unlimited

Maximum pages crawled per day

500

Unlimited

What about existing instances? 

If you created instances before this release, they continue to work exactly as they do today. Your R2 buckets, Vectorize indexes, and Browser Run usage remain on your account and are billed as before. We’ll share migration details for existing instances soon.

Get started today

Search is one of the most fundamental things an agent can do. With AI Search, you don’t have to build the infrastructure to make it happen. Create an instance, give it your data, and let your agents search it.

Get started today by running this command to create your first instance:

npx wrangler ai-search create my-search

Check out the docs and come tell us what you’re building on the Cloudflare Developer Discord.

Cloudflare Email Service: now in public beta. Ready for your agents

Post Syndicated from Thomas Gauvin original https://blog.cloudflare.com/email-for-agents/

Email is the most accessible interface in the world. It is ubiquitous. There’s no need for a custom chat application, no custom SDK for each channel. Everyone already has an email address, which means everyone can already interact with your application or agent. And your agent can interact with anyone.

If you are building an application, you already rely on email for signups, notifications, and invoices. Increasingly, it is not just your application logic that needs this channel. Your agents do, too. During our private beta, we talked to developers who are building exactly this: customer support agents, invoice processing pipelines, account verification flows, multi-agent workflows. All built on top of email. The pattern is clear: email is becoming a core interface for agents, and developers need infrastructure purpose-built for it.

Cloudflare Email Service is that piece. With Email Routing, you can receive email to your application or agent. With Email Sending, you can reply to emails or send outbounds to notify your users when your agents are done doing work. And with the rest of the developer platform, you can build a full email client and Agents SDK onEmail hook as native functionality. 

Today, as part of Agents Week, Cloudflare Email Service is entering public beta, allowing any application and any agent to send emails. We are also completing the toolkit for building email-native agents: 

  • Email Sending binding, available from your Workers and the Agents SDK 

  • A new Email MCP server

  • Wrangler CLI email commands

  • Skills for coding agents

  • An open-source agentic inbox reference app

Email Sending: now in public beta

Email Sending graduates from private beta to public beta today. You can now send transactional emails directly from Workers with a native Workers binding — no API keys, no secrets management.

export default {
  async fetch(request, env, ctx) {
    await env.EMAIL.send({
      to: "[email protected]",
      from: "[email protected]",
      subject: "Your order has shipped",
      text: "Your order #1234 has shipped and is on its way."
    });
    return new Response("Email sent");
  },
};

Or send from any platform, any language, using the REST API and our TypeScript, Python, and Go SDKs:

curl "https://api.cloudflare.com/client/v4/accounts/{account_id}/email-service/send" \
   --header "Authorization: Bearer <API_TOKEN>" \
   --header "Content-Type: application/json" \
   --data '{
     "to": "[email protected]",
     "from": "[email protected]",
     "subject": "Your order has shipped",
     "text": "Your order #1234 has shipped and is on its way."
   }'

Sending email that actually reaches inboxes usually means wrestling with SPF, DKIM, and DMARC records. When you add your domain to Email Service, we configure all of it automatically. Your emails are authenticated and delivered, not flagged as spam. And because Email Service is a global service built on Cloudflare’s network, your emails are delivered with low latency anywhere in the world.

Combined with Email Routing, which has been free and available for years, you now have complete bidirectional email within a single platform. Receive an email, process it in a Worker, and reply, all without leaving Cloudflare.

For the full deep dive on Email Sending, refer to our Birthday Week announcement. The rest of this post describes what Email Service unlocks for agents.

Agents SDK: your agent is email-native

The Agents SDK for building agents on Cloudflare already has a first-class onEmail hook for receiving and processing inbound email. But until now, your agent could only reply synchronously, or send emails to members of your Cloudflare account. 

With Email Sending, that constraint is gone. This is the difference between a chatbot and an agent.


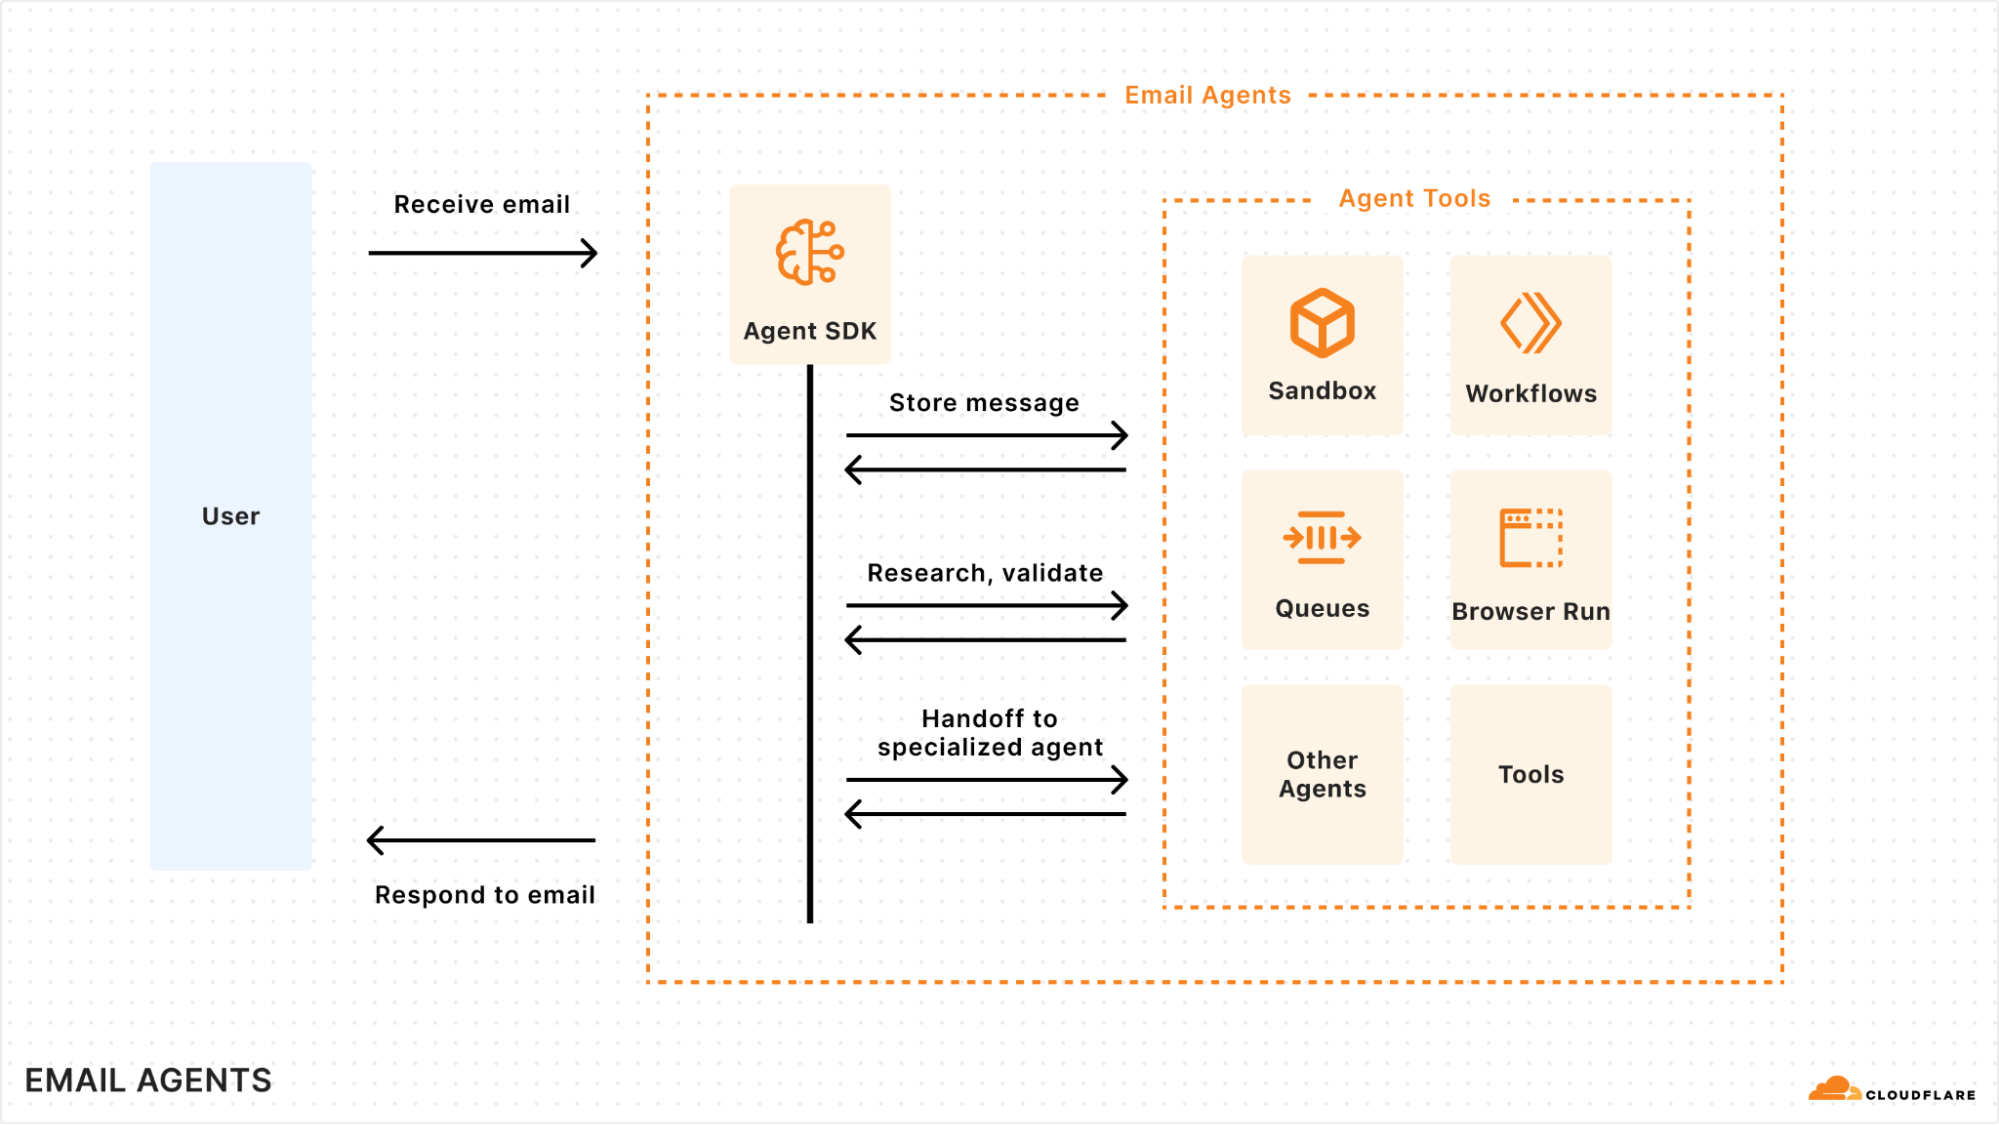
Email agents receive a message, orchestrate work across the platform, and respond asynchronously.

A chatbot responds in the moment or not at all. An agent thinks, acts, and communicates on its own timeline. With Email Sending, your agent can receive a message, spend an hour processing data, check three other systems, and then reply with a complete answer. It can schedule follow-ups. It can escalate when it detects an edge case. It can operate independently. In other words: it can actually do work, not just answer questions. 

Here’s what a support agent looks like with the full pipeline — receive, persist, and reply:

import { Agent, routeAgentEmail } from "agents";
import { createAddressBasedEmailResolver, type AgentEmail } from "agents/email";
import PostalMime from "postal-mime";

export class SupportAgent extends Agent {
  async onEmail(email: AgentEmail) {
    const raw = await email.getRaw();
    const parsed = await PostalMime.parse(raw);

   // Persist in agent state
    this.setState({
      ...this.state,
      ticket: { from: email.from, subject: parsed.subject, body: parsed.text, messageId: parsed.messageId },
    });

    // Kick off long running background agent task 
    // Or place a message on a Queue to be handled by another Worker

    // Reply here or in other Worker handler, like a Queue handler
    await this.sendEmail({
      binding: this.env.EMAIL,
      fromName: "Support Agent",
      from: "[email protected]",
      to: this.state.ticket.from,
      inReplyTo: this.state.ticket.messageId,
      subject: `Re: ${this.state.ticket.subject}`,
      text: `Thanks for reaching out. We received your message about "${this.state.ticket.subject}" and will follow up shortly.`
    });
  }
}

export default {
  async email(message, env) {
    await routeAgentEmail(message, env, {
      resolver: createAddressBasedEmailResolver("SupportAgent"),
    });
  },
} satisfies ExportedHandler<Env>;

If you’re new to the Agents SDK’s email capabilities, here’s what’s happening under the hood.

Each agent gets its own identity from a single domain. The address-based resolver routes [email protected] to a “support” agent instance, [email protected] to a “sales” instance, and so on. You don’t need to provision separate inboxes — the routing is built into the address. You can even use sub-addressing ([email protected]) to route to different agent namespaces and instances.

State persists across emails. Because agents are backed by Durable Objects, calling this.setState() means your agent remembers conversation history, contact information, and context across sessions. The inbox becomes the agent’s memory, without needing a separate database or vector store.

Secure reply routing is built in. When your agent sends an email and expects a reply, you can sign the routing headers with HMAC-SHA256 so that replies route back to the exact agent instance that sent the original message. This prevents attackers from forging headers to route emails to arbitrary agent instances — a security concern that most “email for agents” solutions haven’t addressed.

This is the complete email agent pipeline that teams are building from scratch elsewhere: receive email, parse it, classify it, persist state, kick off async workflows, reply or escalate — all within a single Agent class, deployed globally on Cloudflare’s network.

Email tooling for your agents: MCP server, Wrangler CLI, and skills

Email Service isn’t only for agents running on Cloudflare. Agents run everywhere, whether it’s coding agents like Claude Code, Cursor, or Copilot running locally or in remote environments, or production agents running in containers or external clouds. They all need to send email from those environments. We’re shipping three integrations that make Email Service accessible to any agent, regardless of where it runs.

Email is now available through the Cloudflare MCP server, the same Code Mode-powered server that gives agents access to the entire Cloudflare API. With this MCP server, your agent can discover and call the Email endpoints to send and configure emails. You can send an email with a simple prompt:

"Send me a notification email at [email protected] from my staging domain when the build completes"

For agents running on a computer or a sandbox with bash access, the Wrangler CLI solves the MCP context window problem that we discussed in the Code Mode blog post — tool definitions can consume tens of thousands of tokens before your agent even starts processing a single message. With Wrangler, your agent starts with near-zero context overhead and discovers capabilities on demand through `–help` commands. Here is how your agent can send an email via Wrangler:

wrangler email send \
  --to "[email protected]" \
  --from "[email protected]" \
  --subject "Build completed" \
  --text "The build passed. Deployed to staging."

Regardless of whether you give your agent the Cloudflare MCP or the Wrangler CLI, your agent will be able to now send emails on your behalf with just a prompt.

Skills

We are also publishing a Cloudflare Email Service skill. It gives your agents complete guidance: configuring the Workers binding, sending emails via the REST API or SDKs, handling inbound email with Email Routing configuration, building with Agents SDK, and managing email through Wrangler CLI or MCP. It also covers deliverability best practices and how to craft good transactional emails that land in inboxes rather than spam. Drop it into your project and your coding agent has everything needed to build production-ready email on Cloudflare.

Open-sourcing tools for email agents

During the private beta, we also experimented with email agents. It became clear that you often want to keep the human-in-the-loop element to review emails and see what the agent is doing.The best way to do that is to have a fully featured email client with agent automations built-in.

That’s why we built Agentic Inbox: a reference application with full conversation threading, email rendering, receiving and storing emails and their attachments, and automatically replying to emails. It includes a dedicated MCP server built-in, so external agents can draft emails for your review before sending from your agentic-inbox. 


We’re open-sourcing Agentic Inbox as a reference application for how to build a full email application using Email Routing for inbound, Email Sending for outbound, Workers AI for classification, R2 for attachments, and Agents SDK for stateful agent logic. You can deploy it today to get a full inbox, email client and agent for your emails, with the click of a button.

We want email agent tooling to be composable and reusable. Rather than every team rebuilding the same inbound-classify-reply pipeline, start with this reference application. Fork it, extend it, use it as a starting point for your own email agents that fit your workflows.

Try it out today

Email is where the world’s most important workflows live, but for agents, it has often been a difficult channel to reach. With Email Sending now in public beta, Cloudflare Email Service becomes a complete platform for bidirectional communication, making the inbox a first-class interface for your agents.

Whether you’re building a support agent that meets customers in their inbox or a background process that keeps your team updated in real time, your agents now have a seamless way to communicate on a global scale. The inbox is no longer a silo. Now it’s one more place for your agents to be helpful.


Watch on Cloudflare TV

Add voice to your agent

Post Syndicated from Sunil Pai original https://blog.cloudflare.com/voice-agents/

For many of us, our first experiences with AI agents have been through typing into a chat box. And for those of us using agents day to day, we have likely gotten very good at writing detailed prompts or markdown files to guide them.

But some of the moments where agents would be most useful are not always text-first. You might be on a long commute, juggling a few open sessions, or just wanting to speak naturally to an agent, have it speak back, and continue the interaction.

Adding voice to an agent should not require moving that agent into a separate voice framework. Today, we are releasing an experimental voice pipeline for the Agents SDK.

With @cloudflare/voice, you can add real-time voice to the same Agent architecture you already use. Voice just becomes another way you can talk to the same Durable Object, with the same tools, persistence, and WebSocket connection model that the Agents SDK already provides. 

@cloudflare/voice is an experimental package for the Agents SDK that provides: 

  • withVoice(Agent) for full conversation voice agents

  • withVoiceInput(Agent) for speech-to-text-only use cases, like dictation or voice search 

  • useVoiceAgent and useVoiceInput hooks for React apps 

  • VoiceClient for framework-agnostic clients 

  • Built-in Workers AI providers, so that you can get started without external API keys: 

This means you can now build an agent that users can talk to in real time over a single WebSocket connection, while keeping the same Agent class, Durable Object instance, and the same SQLite-backed conversation history. 

Just as importantly, we want this to be bigger than one fixed default stack. The provider interfaces in @cloudflare/voice are intentionally small, and we want speech, telephony, and transport providers to build with us, so developers can mix and match the right components for their use case, instead of being locked into a single voice architecture.

Get started with voice

Here’s the minimal server-side pattern for a voice agent in the Agents SDK: 

import { Agent, routeAgentRequest } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAITTS,
  type VoiceTurnContext
} from "@cloudflare/voice";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async onTurn(transcript: string, context: VoiceTurnContext) {
    return `You said: ${transcript}`;
  }
}

export default {
  async fetch(request: Request, env: Env) {
    return (
      (await routeAgentRequest(request, env)) ??
      new Response("Not found", { status: 404 })
    );
  }
} satisfies ExportedHandler<Env>;

That’s the whole server. You add a continuous transcriber, a text-to-speech provider, and implement onTurn().

On the client side, you can connect to it with a React hook: 

import { useVoiceAgent } from "@cloudflare/voice/react";

function App() {
  const {
    status,
    transcript,
    interimTranscript,
    startCall,
    endCall,
    toggleMute
  } = useVoiceAgent({ agent: "my-agent" });

  return (
    <div>
      <p>Status: {status}</p>
      {interimTranscript && <p><em>{interimTranscript}</em></p>}
      <ul>
        {transcript.map((msg, i) => (
          <li key={i}>
            <strong>{msg.role}:</strong> {msg.text}
          </li>
        ))}
      </ul>
      <button onClick={startCall}>Start Call</button>
      <button onClick={endCall}>End Call</button>
      <button onClick={toggleMute}>Mute / Unmute</button>
    </div>
  );
}

If you are not using React, you can use VoiceClient directly from @cloudflare/voice/client

How the voice pipeline works

With the Agents SDK, every agent is a Durable Object — a stateful, addressable server instance with its own SQLite database, WebSocket connections, and application logic. The voice pipeline extends this model instead of replacing it. 

At a high level, the flow looks like this:


Here’s how the pipeline breaks down, step by step:

  1. Audio transport: The browser captures microphone audio and streams 16 kHz mono PCM over the same WebSocket connection the agent already uses.

  2. STT session setup:  When the call starts, the agent creates a continuous transcriber session that lives for the duration of the call. 

  3. STT input: Audio streams continuously into that session.

  4. STT turn detection: The speech-to-text model itself decides when the user has finished an utterance and emits a stable transcript for that turn. 

  5. LLM/application logic: The voice pipeline passes that transcript to your onTurn() method.

  6. TTS output: Your response is synthesized to audio and sent back to the client. If onTurn() returns a stream, the pipeline sentence-chunks it and starts sending audio as sentences are ready. 

  7. Persistence: The user and agent messages are persisted in SQLite, so conversation history survives reconnections and deployments.  

Why voice should grow with the rest of your agent

Many voice frameworks focus on the voice loop itself: audio in, transcription, model response, audio out. Those are important primitives, but there’s a lot more to an agent than just voice. 

Real agents running in production will grow. They need state, scheduling, persistence, tools, workflows, telephony, and ways to keep all of that consistent across channels. As your agent grows in complexity, voice stops being a standalone feature and becomes part of a larger system. 

We wanted voice in the Agents SDK to start from that assumption. Instead of building voice as a separate stack, we built it on top of the same Durable Object-based agent platform, so you can pull in the rest of the primitives you need without re-architecting the application later.

Voice and text share the same state

A user might start by typing, switch to voice, and go back to text. With Agents SDK, these are all just different inputs to the same agent. The same conversation history lives in SQLite, and the same tools are available. This gives you both a cleaner mental model and a much simpler application architecture to reason about. 

Lower latency comes from…

a shorter network path 

Voice experiences feel good or bad very quickly. Once a user stops speaking, the system needs to transcribe, think, and start speaking back fast enough to feel conversational. 

A lot of voice latency is not pure model time. It’s the cost of bouncing audio and text between different services in different places. Audio needs to go to STT, transcripts go to an LLM, and responses go to a TTS model – and each handoff adds network overhead. 

With the Agents SDK voice pipeline, the agent runs on Cloudflare’s network, and the built-in providers use Workers AI bindings. That keeps the pipeline tighter and reduces the amount of infrastructure you have to stitch together yourself. 

built-in streaming

A voice agent interaction feels much more natural if it speaks the first sentence quickly (also called Time-to-First Audio). When onTurn() returns a stream, the pipeline chunks it into sentences and starts synthesis as sentences complete. That means the user can hear the beginning of the answer while the rest is still being generated. 

A more realistic backend 

Here is a fuller example that streams an LLM response and starts speaking it back, sentence by sentence:

import { Agent, routeAgentRequest } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAITTS,
  type VoiceTurnContext
} from "@cloudflare/voice";
import { streamText } from "ai";
import { createWorkersAI } from "workers-ai-provider";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async onTurn(transcript: string, context: VoiceTurnContext) {
    const ai = createWorkersAI({ binding: this.env.AI });

    const result = streamText({
      model: ai("@cf/cloudflare/gpt-oss-20b"),
      system: "You are a helpful voice assistant. Be concise.",
      messages: [
        ...context.messages.map((m) => ({
          role: m.role as "user" | "assistant",
          content: m.content
        })),
        { role: "user" as const, content: transcript }
      ],
      abortSignal: context.signal
    });

    return result.textStream;
  }
}

export default {
  async fetch(request: Request, env: Env) {
    return (
      (await routeAgentRequest(request, env)) ??
      new Response("Not found", { status: 404 })
    );
  }
} satisfies ExportedHandler<Env>;

Context.messages gives you recent SQLite-backed conversation history, and context.signal lets the pipeline abort the LLM call if the user interrupts. 

Voice as an input: withVoiceInput

Not every speech interface needs to speak back. Sometimes you might want dictation, transcription, or voice search. For these use cases, you can use withVoiceInput

import { Agent, type Connection } from "agents";
import { withVoiceInput, WorkersAINova3STT } from "@cloudflare/voice";

const InputAgent = withVoiceInput(Agent);

export class DictationAgent extends InputAgent<Env> {
  transcriber = new WorkersAINova3STT(this.env.AI);

  onTranscript(text: string, _connection: Connection) {
    console.log("User said:", text);
  }
}

On the client, useVoiceInput gives you a lightweight interface centered on transcriptions: 

import { useVoiceInput } from "@cloudflare/voice/react";

const { transcript, interimTranscript, isListening, start, stop, clear } =
  useVoiceInput({ agent: "DictationAgent" });

This is useful when speech is an input method, and you don’t need a full conversational loop. 

Voice and text on the same connection

The same client can call sendText(“What’s the weather?”), which bypasses STT and sends the text directly to onTurn(). During an active call, the response can be spoken and shown as text. Outside a call, it can remain text-only. 

This gives you a genuinely multimodal agent, without splitting the implementation into different code paths. 

What else can you build? 

Because a voice agent is still an agent, all the normal Agents SDK capabilities still apply. 

Tools and scheduling

You can greet a caller when a session starts: 

import { Agent, type Connection } from "agents";
import { withVoice, WorkersAIFluxSTT, WorkersAITTS } from "@cloudflare/voice";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async onTurn(transcript: string) {
    return `You said: ${transcript}`;
  }

  async onCallStart(connection: Connection) {
    await this.speak(connection, "Hi! How can I help you today?");
  }
}

You can schedule spoken reminders and expose tools to your LLM just like any other agent: 

import { Agent } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAITTS,
  type VoiceTurnContext
} from "@cloudflare/voice";
import { streamText, tool } from "ai";
import { createWorkersAI } from "workers-ai-provider";
import { z } from "zod";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async speakReminder(payload: { message: string }) {
    await this.speakAll(`Reminder: ${payload.message}`);
  }

  async onTurn(transcript: string, context: VoiceTurnContext) {
    const ai = createWorkersAI({ binding: this.env.AI });

    const result = streamText({
      model: ai("@cf/cloudflare/gpt-oss-20b"),
      messages: [
        ...context.messages.map((m) => ({
          role: m.role as "user" | "assistant",
          content: m.content
        })),
        { role: "user" as const, content: transcript }
      ],
      tools: {
        set_reminder: tool({
          description: "Set a spoken reminder after a delay",
          inputSchema: z.object({
            message: z.string(),
            delay_seconds: z.number()
          }),
          execute: async ({ message, delay_seconds }) => {
            await this.schedule(delay_seconds, "speakReminder", { message });
            return { confirmed: true };
          }
        })
      },
      abortSignal: context.signal
    });

    return result.textStream;
  }
}

Runtime model switching

The voice pipeline also lets you choose a transcription model dynamically per connection. 

For example, you might prefer Flux for conversational turn-taking and Nova 3 for higher-accuracy dictation. You can switch at runtime by overriding createTranscriber()

import { Agent, type Connection } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAINova3STT,
  WorkersAITTS,
  type Transcriber
} from "@cloudflare/voice";

export class MyAgent extends VoiceAgent<Env> {
  tts = new WorkersAITTS(this.env.AI);

  createTranscriber(connection: Connection): Transcriber {
    const url = new URL(connection.url ?? "http://localhost");
    const model = url.searchParams.get("model");
    if (model === "nova-3") {
      return new WorkersAINova3STT(this.env.AI);
    }
    return new WorkersAIFluxSTT(this.env.AI);
  }
}

On the client, you can pass query parameters through the hook: 

const voiceAgent = useVoiceAgent({
  agent: "my-voice-agent",
  query: { model: "nova-3" }
});

Pipeline hooks

You can also intercept data between stages: 

  • afterTranscribe(transcript, connection)

  • beforeSynthesize(text, connection)

  • afterSynthesize(audio, text, connection)

These hooks are useful for content filtering, text normalization, language-specific transformations, or custom logging. 

Telephone and transport options

By default, the voice pipeline uses a single WebSocket connection as the simplest path for 1:1 voice agents. But that’s not the only option. 

Phone calls via Twilio

You can connect phone calls to the same agent using the Twilio adapter:

import { TwilioAdapter } from "@cloudflare/voice-twilio";

export default {
  async fetch(request: Request, env: Env) {
    if (new URL(request.url).pathname === "/twilio") {
      return TwilioAdapter.handleRequest(request, env, "MyAgent");
    }

    return (
      (await routeAgentRequest(request, env)) ??
      new Response("Not found", { status: 404 })
    );
  }
};

This lets the same agent handle web voice, text input, and phone calls. 

One caveat: the default Workers AI TTS provider returns MP3, while Twilio expects mulaw 8kHz audio. For production telephony, you may want to use a TTS provider that outputs PCM or mulaw directly. 

WebRTC

If you need a transport that is better suited to difficult network conditions or will include multiple participants, the voice package also includes SFU utilities and supports custom transports. The default model is WebSocket-native today, but we plan to develop more adapters to connect to our global SFU infrastructure

Build with us 

The voice pipeline is provider-agnostic by design. 

Under the hood, each stage is defined by a small interface: a transcriber opens a continuous session and accepts audio frames as they arrive, while a TTS provider takes text and returns audio. If a provider can stream audio output, the pipeline can use that too.

interface Transcriber {
  createSession(options?: TranscriberSessionOptions): TranscriberSession;
}

interface TranscriberSession {
  feed(chunk: ArrayBuffer): void;
  close(): void;
}

interface TTSProvider {
  synthesize(text: string, signal?: AbortSignal): Promise<ArrayBuffer | null>;
}

We didn’t want voice support in Agents SDK to only work with one fixed combination of models and transports. We wanted the default path to be simple, while still making it easy to plug in other providers as the ecosystem grows. 

The built-in providers use Workers AI, so you can get started without external API keys:

  • WorkersAIFluxSTT for conversational streaming STT

  • WorkersAINova3STT for dictation-style streaming STT

  • WorkersAITTS for text-to-speech

But the bigger goal is interoperability. If you maintain a speech or voice service, these interfaces are small enough to implement without needing to understand the rest of the SDK internals. If your STT provider accepts streaming audio and can detect utterance boundaries, it can satisfy the transcriber interface. If your TTS provider can stream audio output, even better. 

We would love to work on interoperability with:

  • STT providers like AssemblyAI, Rev.ai, Speechmatics, or any service with a real-time transcription API

  • TTS providers like PlayHT, LMNT, Cartesia, Coqui, Amazon Polly, or Google Cloud TTS

  • telephony adapters for platforms like Vonage, Telnyx, or Bandwidth

  • transport implementations for WebRTC data channels, SFU bridges, and other audio transport layers

We are also interested in collaborations that go beyond individual providers:

  • latency benchmarking across STT + LLM + TTS combinations

  • multilingual support and better documentation for non-English voice agents

  • accessibility work, especially around multimodal interfaces and speech impairments

If you are building voice infrastructure and want to see a first-class integration, open a PR or reach out.

Try it now

The voice pipeline is available today as an experimental package:

npm create cloudflare@latest -- --template cloudflare/agents-starter

Add @cloudflare/voice, give your agent a transcriber and a TTS provider, deploy it, and start talking to it. You can also read the API reference.

If you build something interesting, open an issue or PR on github.com/cloudflare/agents. Voice should not require a separate stack, and we think the best voice agents will be the ones built on the same durable application model as everything else.


Rearchitecting the Workflows control plane for the agentic era

Post Syndicated from Luís Duarte original https://blog.cloudflare.com/workflows-v2/

When we originally built Workflows, our durable execution engine for multi-step applications, it was designed for a world in which workflows were triggered by human actions, like a user signing up or placing an order. For use cases like onboarding flows, workflows only had to support one instance per person — and people can only click so fast. 

Over time, what we’ve actually seen is a quantitative shift in the workload and access pattern: fewer human-triggered workflows, and more agent-triggered workflows, created at machine speed. 

As agents become persistent and autonomous infrastructure, operating on behalf of users for hours or days, they need a durable, asynchronous execution engine for the work they are doing. Workflows provides exactly that: every step is independently retryable, the workflow can pause for human-in-the-loop approval, and each instance survives failures without losing progress.  

Moreover, workflows themselves are being used to implement agent loops and serve as the durable harnesses that manage and keep agents alive. Our Agents SDK integration accelerated this, making it easy for agents to spawn workflow instances and get real-time progress back. A single agent session can now kick off dozens of workflows, and many agents running concurrently means thousands of instances created in seconds. With Project Think now available, we anticipate that velocity will only increase.

To help developers scale their agents and applications on Workflows, we are excited to announce that we now support:

  • 50,000 concurrent instances (number of workflow executions running in parallel), originally 4,500

  • 300 instances/second created per account, previously 100

  • 2 million queued instances (meaning instances that have been created or awoken and are waiting for a concurrency slot) per workflow, up from 1 million

We redesigned the Workflows control plane from usage data and first principles to support these increases. For V1 of the control plane, a single Durable Object (DO) could serve as the central registry and coordinator of an entire account. For V2, we built two new components to help horizontally scale the system and alleviate the bottlenecks that V1 introduced, before migrating all customers — with live traffic — seamlessly onto the new version.

V1: initial architecture of Workflows

As described in our public beta blog post, we built Workflows entirely on our own developer platform. Fundamentally, a workflow is a series of durable steps, each independently retryable, that can execute tasks, wait for external events, or sleep until a predetermined time. 

export class MyWorkflow extends WorkflowEntrypoint {

  async run(event, step) {
    const data = await step.do("fetch-data", async () => {
      return fetchFromAPI();
    });

    const approval = await step.waitForEvent("approval", {
      type: "approval",
      timeout: "24 hours",
    });

    await step.do("process-and-save", async () => {
      return store(transform(data));
    });
  }
}

To trigger each instance, execute its logic, and store its metadata, we leverage SQLite-backed Durable Objects, which are a simple but powerful primitive for coordination and storage within a distributed system. 

In the control plane, some Durable Objects — like the Engine, which executes the actual workflow instance, including its step, retry, and sleep logic — are spun up at a ratio of 1:1 per instance. On the other hand, the Account is an account-level Durable Object that manages all workflows and workflow instances for that account.


To learn more about the V1 control plane, refer to our Workflows announcement blog post.

After we launched Workflows into beta, we were thrilled to see customers quickly scaling their use of the product, but we also realized that having a single Durable Object to store all that account-level information introduced a bottleneck. Many customers needed to create and execute hundreds or even thousands of Workflow instances per minute, which could quickly overwhelm the Account in our original architecture. The original rate limits — 4,500 concurrency slots and 100 instance creations per 10 seconds — were a result of this limitation. 

On the V1 control plane, these limits were a hard cap. Any and all operations depending on Account, including create, update, and list, had to go through that single DO. Users with high concurrency workloads could have thousands of instances starting and ending at any given moment, building up to thousands of requests per second to Account. To solve for this, we rearchitected the workflow control plane such that it horizontally scales to higher concurrency and creation rate limits. 

V2: horizontal scale for higher throughput

For the new version, we rethought every single operation from the ground up with the goal of optimizing for high-volume workflows. Ultimately, Workflows should scale to support whatever developers need – whether that is thousands of instances created per second or millions of instances running at a time. We also wanted to ensure that V2 allowed for flexible limits, which we can toggle and continue increasing, rather than the hard cap which V1 limits imposed. After many design iterations, we settled on the following pillars for our new architecture: 

  • The source of truth for the existence of a given instance should be its Engine and nothing else. 

    • In the V1 control plane architecture, we lacked a check before queuing the instance as to whether its Engine actually existed. This allowed for a bad state where an instance may have been queued without its corresponding Engine having spun up. 

    • Instance lifecycle and liveness mechanisms must be horizontally scalable per-workflow and distributed throughout many regions.

  • The new Account singleton should only store the minimum necessary metadata and have an invariant maximum amount of concurrent requests.


There are two new, critical components in the V2 control plane which allowed us to improve the scalability of Workflows: SousChef and Gatekeeper. The first component, SousChef, is a “second in command” to the Account. Recall that previously, the Account managed the metadata and lifecycle for all of the instances across all of the workflows within a given account. SousChef was introduced to keep track of metadata and lifecycle on a subset of instances in a given workflow. Within an account, a distribution of SousChefs can then report back to Account in a more efficient and manageable way. (An added benefit of this design: not only did we already have per-account isolation, but we also inadvertently gained “per-workflow” isolation within the same account, since each SousChef only takes care of one specific workflow).

The second component, Gatekeeper, is a mechanism to distribute concurrency “slots” (derived from concurrency limits) across all SousChefs within the account. It acts as a leasing system. When an instance is created, it is randomly assigned to one of the SousChefs within that account. Then the SousChef makes a request to Account to trigger that instance. Either a slot is granted, or the instance is queued. Once the slot is granted, the SousChef triggers execution of the instance and assumes responsibility that the instance never gets stuck. 

Gatekeeper was needed to make sure that Engines never overloaded their Account (a pressing risk on V1) so every communication between SousChefs and their Account happens on a periodic cycle, once per second — each cycle will also batch all slot requests, ensuring that only one JSRPC call is made. This ensures the instance creation rate can never overload or influence the most important component, Account (as an aside: if the SousChef count is too high, we rate-limit calls or spread across different SousChefs throughout different time periods). Also, this periodic property allows us to preserve fairness on older instances and to ensure max-min fairness through the many SousChefs, allowing them all to progress. For example, if an instance wakes up, it should be prioritized for a slot over a newly created instance, but each SousChef ensures that its own instances do not get stuck.

This architecture is more distributed, and therefore, more scalable. Now, when an instance is created, the request path is:

  1. Check control plane version

  2. Check if a cached version of the workflow and version details is available in that location

    1. If not, check Account to get workflow name, unique ID, and version, and cache that information

  3. Store only necessary metadata (instance payload, creation date) onto its own Engine

So, how does Engine tell the control plane that it now exists? That happens in the background after instance metadata is set. As background operations on a Durable Object can fail, due to eviction or server failure, we also set an “alarm” on Engine in the creation hot-path. That way, if the background task does not finish, the alarm ensures that the instance will begin. 

A Durable Object alarm allows a Durable Object instance to be awakened at a fine-grained time in the future with an at-least-once execution model, with automatic retries built in. We extensively use this combination of background “tasks” and alarms to remove operations off the hot-path while still ensuring that everything will happen as planned. That’s how we keep critical operations like creating an instance fast without ever compromising on reliability. 

Other than unlocking scale, this version of the control plane means that: 

  • Instance listing performance is faster, and actually consistent with cursor pagination; 

  • Any operation on an instance does exactly one network hop (as it can go directly to its Engine, ensuring that eyeball request latency is as small as we can manage);

  • We can ensure that more instances are actually behaving correctly (by running on time) concurrently (and correct them if not, making sure that Engines are never late to continue execution).

V1 → V2 migration

Now that we had a new version of the Workflows control plane that can handle a higher volume of user load, we needed to do the “boring” part: migrating our customers and instances to the new system. At Cloudflare’s scale, this becomes a problem in and of itself, so the “boring” part becomes the biggest challenge. Well before its one-year mark, Workflows had already racked up millions of instances and thousands of customers. Also, some tech debt on V1’s control plane meant that a queued instance might not have its own Engine Durable Object created yet, complicating matters further.

Such a migration is tricky because customers might have instances running at any given moment; we needed a way to add the SousChef and Gatekeeper components into older accounts without causing any disruption or downtime.

We ultimately decided that we would migrate existing Accounts (which we’ll refer to as AccountOlds) to behave like SousChefs. By persisting the Account DOs, we maintained the instance metadata, and simply converted the DO into a SousChef “DO”: 

// You might be wondering what's this SousChef class? This is the SousChef DO class!
import { SousChef } from "@repo/souschef";

class AccountOld extends DurableObject {
  constructor(state: DurableObjectState, env: Env) {
    // We added the following snippet to the end of our AccountOld DO's
    // constructor. This ensures that if we want, we can use any primitive
    // that is available on SousChef DO
    if (this.currentVersion === ControlPlaneVersions.SOUS_CHEFS) {
      this.sousChef = new SousChef(this.ctx, this.env);
      await this.sousChef.setup()
    }
  }

  async updateInstance(params: UpdateInstanceParams) {
    if (this.currentVersion === ControlPlaneVersions.SOUS_CHEFS) {
      assert(this.sousChef !== undefined, 'SousChef must exist on v2');
      return this.sousChef.updateInstance(params);
    }

    // old logic remains the same
  }

  @RequiresVersion<AccountOld>(ControlPlaneVersions.V1)
  async getMetadata() {
    // this method can only be run if 
    // this.currentVersion === ControlPlaneVersions.V1
  }
}

We can instantiate the SousChef class within the AccountOld because the SQL tables that track instance metadata, on both SousChefs and AccountOld DOs, are the same on both. As such, we could just decide which version of the code to use. If this hadn’t been the case, we would have been forced to migrate the metadata of millions of instances, which would have made the migration more difficult and longer running for each account. So, how did the migration work?

First, we prepared AccountOld DOs to be switched to behave as SousChefs (which meant creating a release with a version of the snippet above). Then, we enabled control plane V2 per account, which triggered the next three steps roughly at the same time:

  • All new instance creation requests are now routed to the new SousChefs (SousChefs are created when they receive the first request), new instances never go to AccountOld again;

  • AccountOld DOs start migrating themselves to behave like SousChefs;

  • The new Account DO is spun up with the corresponding metadata.

After all accounts were migrated to the new control plane version, we were able to sunset AccountOld DOs as their instance retention periods expired. Once all instances on all accounts on AccountOlds were migrated, we could spin down those DOs permanently. The migration was completed with no downtime in a process that truly felt like changing a car’s wheels while driving.

Try it out

If you are new to Workflows, try our Get Started guide or build your first durable agent with Workflows.

If your use case requires higher limits than our new defaults — a concurrency limit of 50,000 slots and account-level creation rate limit of 300 instances per second, 100 per workflow — reach out via your account team or the Workers Limit Request Form. You can also reach out with feedback, feature requests, or just to share how you are using Workflows on our Discord server.

Browser Run: give your agents a browser

Post Syndicated from Kathy Liao original https://blog.cloudflare.com/browser-run-for-ai-agents/

AI agents need to interact with the web. To do that, they need a browser. They need to navigate sites, read pages, fill forms, extract data, and take screenshots. They need to observe whether things are working as expected, with a way for their humans to step in if needed. And they need to do all of this at scale.

Today, we’re renaming Browser Rendering to Browser Run, and shipping key features that make it the browser for AI agents. The name Browser Rendering never fully captured what the product does. Browser Run lets you run full browser sessions on Cloudflare’s global network, drive them with code or AI, record and replay sessions, crawl pages for content, debug in real time, and let humans intervene when your agent needs help. 

Here’s what’s new:

  • Live View: see what your agent sees and is doing, in real time. Know instantly if things are working, and when they’re not, see exactly why.

  • Human in the Loop: when your agent hits a snag like a login page or unexpected edge case, it can hand off to a human instead of failing. The human steps in, resolves, then hands back control.

  • Chrome DevTools Protocol (CDP) Endpoint: the Chrome DevTools Protocol is how agents control browsers. Browser Run now exposes it directly, so agents get maximum control over the browser and existing CDP scripts work on Cloudflare.

  • MCP Client Support: AI coding agents like Claude Desktop, Cursor, and OpenCode can now use Browser Run as their remote browser.

  • WebMCP Support: agents will outnumber humans using the web. WebMCP allows websites to declare what actions are available for agents to discover and call, making navigation more reliable.

  • Session Recordings: capture every browser session for debugging purposes. When something goes wrong, you have the full recording with DOM changes, user interactions, and page navigation.

  • Higher limits: run more tasks at once with 120 concurrent browsers, up from 30. 

An AI agent searching Amazon for an orange lava lamp, comparing options, and handing off to a human when sign-in is required to complete the purchase

Everything an agent needs

Let’s think about what agents need when browsing the web and how each feature fits in:

What an agent needs Browser Run (formerly Browser Rendering)
1) Browsers on-demand Chrome browser on Cloudflare’s global network
2) A way to control the browser Take actions like navigate, click, fill forms, screenshot, and more with Puppeteer, Playwright, CDP (new), MCP Client Support (new) and WebMCP (new)
3) Observability Live View (new), Session Recordings (new), and Dashboard redesign (new)
4) Human intervention Human in the Loop (new)
5) Scale 10 requests/second for Quick Actions, 120 concurrent browsers (4x increase)

1) Open a browser

First, an agent needs a browser. With Browser Run, agents can spin up a headless Chrome instance on Cloudflare’s global network, on demand. No infrastructure to manage, no Chrome versions to maintain. Browser sessions open near users for low latency, and scale up and down as needed. Pair Browser Run with the Agents SDK to build long-running agents that browse the web, remember everything, and act on their own. 

2) Take actions

Once your agent has a browser, it needs ways to control it. Browser Run supports multiple approaches: new low-level protocol access with the Chrome DevTools Protocol (CDP) and WebMCP, in addition to existing higher-level automation using Puppeteer and Playwright, and Quick Actions for simple tasks. Let’s look at the details.

Chrome DevTools Protocol (CDP) endpoint

The Chrome DevTools Protocol (CDP) is the low-level protocol that powers browser automation. Exposing CDP directly means the growing ecosystem of agent tools and existing CDP automation scripts can use Browser Run. When you open Chrome DevTools and inspect a page, CDP is what’s running underneath. Puppeteer, Playwright, and most agent frameworks are built on top of it.

Every way that you have been using Browser Run has actually been through CDP already. What’s new is that we’re now exposing CDP directly as an endpoint. This matters for agents because CDP gives agents the most control possible over the browser. Agent frameworks already speak CDP natively, and can now connect to Browser Run directly. CDP also unlocks browser actions that aren’t available through Puppeteer or Playwright, like JavaScript debugging. And because you’re working with raw CDP messages instead of going through higher-level libraries, you can pass messages directly to models for more token-efficient browser control.

If you already have CDP automation scripts running against self-hosted Chrome, they work on Browser Run with a one-line config change. Point your WebSocket URL at Browser Run and stop managing your own browser infrastructure.

// Before: connecting to self-hosted Chrome
const browser = await puppeteer.connect({
  browserWSEndpoint: 'ws://localhost:9222/devtools/browser'
});

// After: connecting to Browser Run
const browser = await puppeteer.connect({
  browserWSEndpoint: 'wss://api.cloudflare.com/client/v4/accounts/<ACCOUNT_ID>/browser-rendering/devtools/browser',
  headers: { 'Authorization': 'Bearer <API_TOKEN>' }
});

The CDP endpoint also makes Browser Run more accessible. You can now connect from any language, any environment, without needing to write a Cloudflare Worker. (If you’re already using Workers, nothing changes.)

Using Browser Run with MCP Clients

Now that Browser Run exposes the Chrome DevTools Protocol (CDP), MCP clients including Claude Desktop, Cursor, Codex, and OpenCode can use Browser Run as their remote browser. The chrome-devtools-mcp package from the Chrome DevTools team is an MCP server that gives your AI coding assistant access to the full power of Chrome DevTools for reliable automation, in-depth debugging, and performance analysis.

Here’s an example of how to configure Browser Run for Claude Desktop:

{
  "mcpServers": {
    "browser-rendering": {
      "command": "npx",
      "args": [
        "-y",
        "chrome-devtools-mcp@latest",
        "--wsEndpoint=wss://api.cloudflare.com/client/v4/accounts/<ACCOUNT_ID>/browser-rendering/devtools/browser?keep_alive=600000",
        "--wsHeaders={\"Authorization\":\"Bearer <API_TOKEN>\"}"
      ]
    }
  }
}

For other MCP clients, see documentation for using Browser Run with MCP clients.

WebMCP support

The Internet was built for humans, so navigating as an AI agent today is unreliable. We’re betting on a future where more agents use the web than humans. In that world, sites need to be agent-friendly.

That’s why we’re launching support for WebMCP, a new browser API from the Google Chrome team that landed in Chromium 146+. WebMCP lets websites expose tools directly to AI agents, declaring what actions are available for agents to discover and call on each page. This helps agents navigate the web more reliably. Instead of agents needing to figure out how to use a site, websites can expose their tools for agents to discover and call

Two APIs make this work:

  • navigator.modelContext allows websites to register their tools

  • navigator.modelContextTesting allows agents to discover and execute those tools

Today, an agent visiting a travel booking site has to figure out the UI by looking at it. With WebMCP, the site declares “here’s a search_flights tool that takes an origin, destination, and date.” The agent calls it directly, without having to loop through slow screenshot-analyze-click loops. This makes navigation more reliable regardless of potential changes to the UI.

Tools are discovered on the page rather than preloaded. This matters for the long tail of the web, where preloading an MCP server for every possible site is not feasible and would bloat the context window. 

Using WebMCP to book a hotel through the Chrome DevTools console, discovering available tools with listTools()

We have an experimental pool with browser instances running Chrome beta so you can test emerging browser features before they reach stable Chrome. We also just shipped Wrangler browser commands that let you manage browser sessions directly from the CLI, letting you create, manage, and view browser sessions directly from your terminal. To access WebMCP-enabled browsers, use the following Wrangler command to create a session in the experimental pool:

npm i -g wrangler@latest
wrangler browser create --lab --keepAlive 300  

Existing ways to use Browser Run

While CDP and WebMCP are new, you could already use Puppeteer, Playwright, or Stagehand for full browser automation through Browser Run. And for simple tasks like capturing screenshots, generating PDFs, and extracting markdown, there are the Quick Action endpoints

/crawl endpoint — crawl web content

We also recently shipped a /crawl endpoint that lets you crawl entire sites with a single API call. Give it a starting URL and pages are automatically discovered and scraped, then returned in your preferred format (HTML, Markdown, and structured JSON), with additional parameters to control crawl depth and scope, skip pages that haven’t changed, and specify certain paths to include or exclude. 

We intentionally built /crawl to be a well-behaved crawler. That means it respects site owner’s preferences out of the box, is a signed agent with a distinct bot ID that is cryptographically signed using Web Bot Auth, a non-customizable User-Agent, and follows robots.txt and AI Crawl Control. It does not bypass Cloudflare’s bot protections or CAPTCHAs. Site owners choose whether their content is accessible and /crawl respects it. 

# Initiate a crawl
curl -X POST 'https://api.cloudflare.com/client/v4/accounts/{account_id}/browser-rendering/crawl' \
  -H 'Authorization: Bearer <apiToken>' \
  -H 'Content-Type: application/json' \
  -d '{
    "url": "https://blog.cloudflare.com/"
  }'

3) Observe

Things don’t always go right the first try. We kept hearing from customers that when their automations failed, they had no idea why. That’s why we’ve added multiple ways to observe what’s happening, so you can see exactly what your agent sees, both live and after the fact. 

Live View

Live View lets you watch your agent’s browser session in real time. Whether you’re debugging an agent or running a long automation script, you see exactly what’s happening as it happens. This includes the page itself, as well as the DOM, console, and network requests. When something goes wrong — the expected button isn’t there, the page needs authentication, or a CAPTCHA appears — you can catch it immediately.

There are two ways to access Live View. From code, obtain the session_id of the browser you want to inspect and open the devtoolsFrontendURL from the response in Chrome. Or from the Cloudflare dashboard, open the new Live Sessions tab in the Browser Run section and click into any active session.

Live View of an AI agent booking a hotel, showing real-time browser activity

Session Recordings

Live View is great when you’re available, but you can’t watch every session. Session Recordings captures DOM changes, mouse and keyboard events, and page navigation as structured JSON so you can replay any session after it ends.

Enable Session Recordings by passing recording:true when launching a browser. After the session closes, you can access the recording in the Cloudflare dashboard from the Runs tab or retrieve recordings via API and replay them with the rrweb-player. Next, we’re adding the ability to inspect DOM state and console output at any point during the recording. 

Session recording replay of a browser automation browsing the Sentry Shop and adding a bomber jacket to the cart

Dashboard Redesign

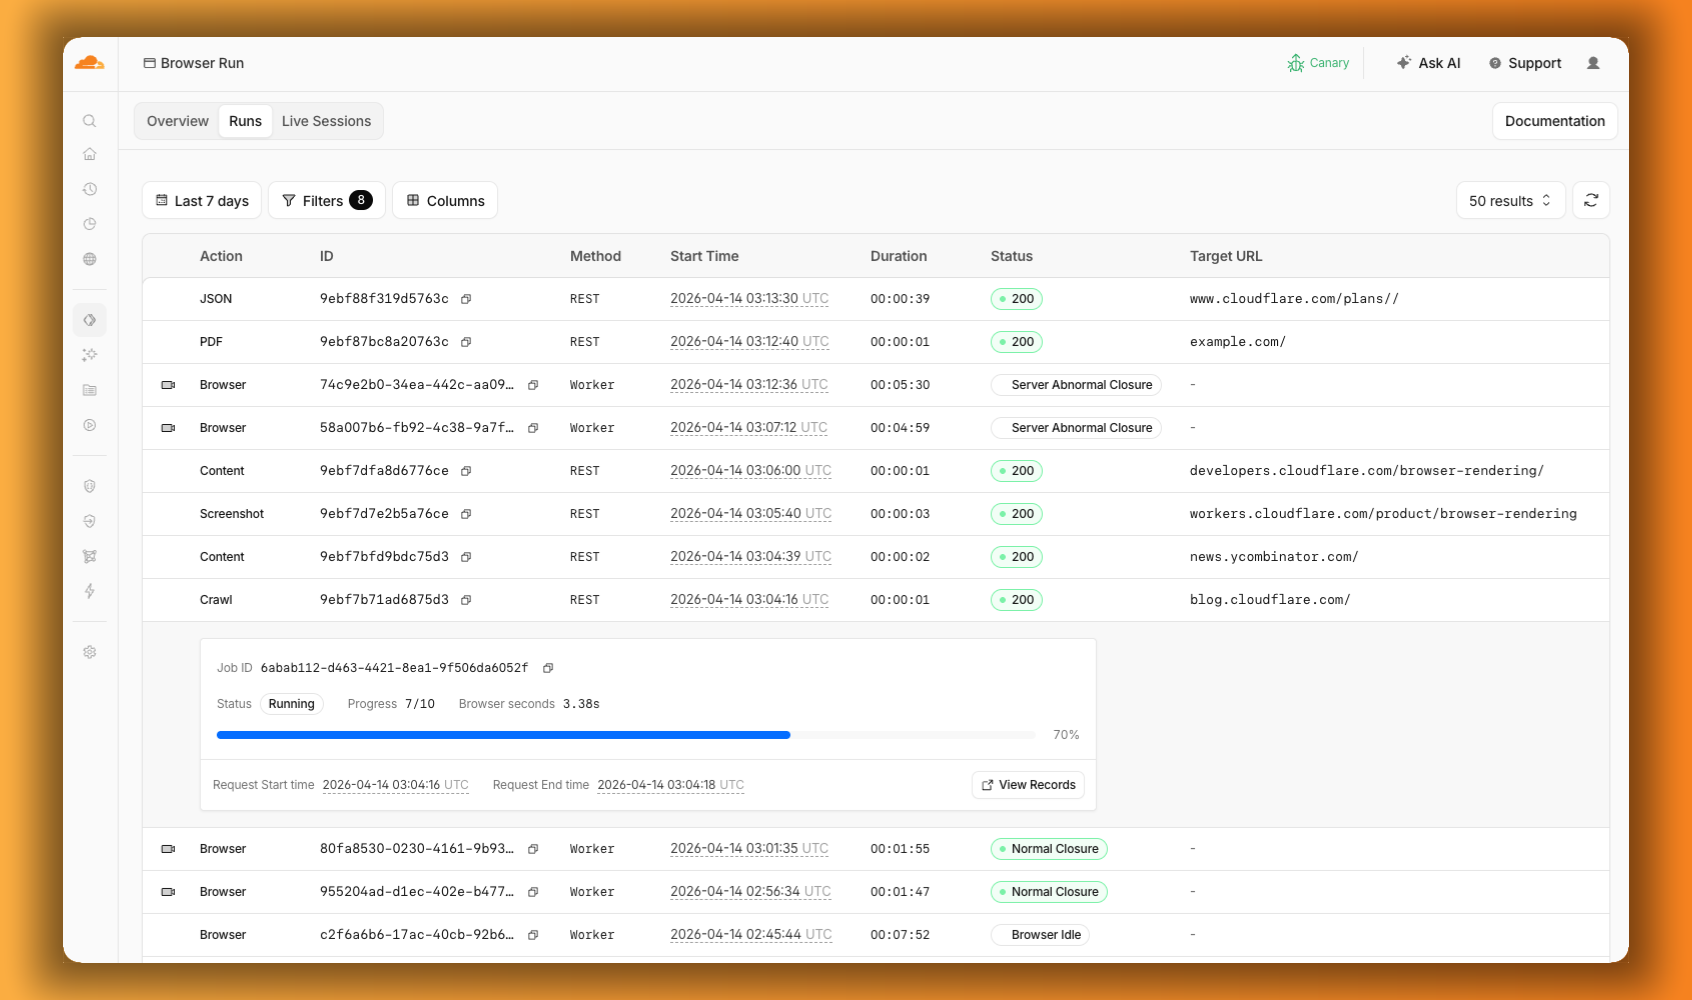
Previously, the Browser Run dashboard only showed logs from browser sessions. Requests for screenshots, PDFs, markdown, and crawls were not visible. The redesigned dashboard changes that. The new Runs tab shows every request. You can filter by endpoint and view details including target URLs, status, and duration. 


The Browser Run dashboard Runs tab showing browser sessions and quick actions like PDF, Screenshot, and Crawl in a single view, with a crawl job expanded to show its progress

4) Intervene

Agents are good, but they’re not perfect. Sometimes they need their human to step in. Browser Run supports Human in the Loop workflows where a human can take control of a live browser session, handle what the automation cannot, then let the session continue. 

Human in the Loop

When automation hits a wall, you don’t have to restart. With Human in the Loop, you can step in and interact with the page directly to click, type, navigate, enter credentials, or submit forms. This unlocks workflows that agents cannot handle.

Today, you can step in by opening the Live View URL for any active session. Next, we’re adding a handoff flow where the agent can signal that it needs help, notify a human to step in, then hand control back to the agent once the issue is resolved.

An AI agent searching Amazon for an orange lava lamp, comparing options, and handing off to a human when sign-in is required to complete the purchase

5) Scale

Customers have asked us to raise limits so that they can do more, faster.

Higher limits

We’ve quadrupled the default concurrent browser limit from 30 to 120. Every session gives you instant access to a browser from a global pool of warm instances, so there’s no cold start waiting for a browser to spin up. In March, we also increased limits for Quick Actions to 10 requests per second. If you need higher limits, they’re available by request.

What’s next

  • Human in the Loop Handoff: today you can intervene in a browser session through Live View. Soon, the agent will be able to signal when it needs help, so you can build in notifications to alert a human to step in.

  • Session Recordings Inspection: you can already scrub through the timeline and replay any session. Soon, you’ll be able to inspect DOM state and console output as well.

  • Traces and Browser Logs: access debugging information without instrumenting your code. Console logs, network requests, timing data. If something broke, you’ll know where.

  • Screenshot, PDF, and markdown directly from Workers: the same simple tasks available through the REST API are coming to Workers Bindings. env.BROWSER.screenshot() just works, with no API tokens needed.

Get started

Browser Run is available today on both the Workers Free and Workers Paid plans. Everything we shipped today — Live View, Human in the Loop, Session Recordings, and higher concurrency limits — is ready to use. 

If you were already using Browser Rendering, everything works the same, just with a new name and more features.  

Check out the documentation to get started.


Project Think: building the next generation of AI agents on Cloudflare

Post Syndicated from Sunil Pai original https://blog.cloudflare.com/project-think/

Today, we’re introducing Project Think: the next generation of the Agents SDK. Project Think is a set of new primitives for building long-running agents (durable execution, sub-agents, sandboxed code execution, persistent sessions) and an opinionated base class that wires them all together. Use the primitives to build exactly what you need, or use the base class to get started fast.

Something happened earlier this year that changed how we think about AI. Tools like Pi, OpenClaw, Claude Code, and Codex proved a simple but powerful idea: give an LLM the ability to read files, write code, execute it, and remember what it learned, and you get something that looks less like a developer tool and more like a general-purpose assistant.

These coding agents aren’t just writing code anymore. People are using them to manage calendars, analyze datasets, negotiate purchases, file taxes, and automate entire business workflows. The pattern is always the same: the agent reads context, reasons about it, writes code to take action, observes the result, and iterates. Code is the universal medium of action.

Our team has been using these coding agents every day. And we kept running into the same walls:

  • They only run on your laptop or an expensive VPS: there’s no sharing, no collaboration, no handoff between devices.

  • They’re expensive when idle: a fixed monthly cost whether the agent is working or not. Scale that to a team, or a company, and it adds up fast.

  • They require management and manual setup: installing dependencies, managing updates, configuring identity and secrets.

And there’s a deeper structural issue. Traditional applications serve many users from one instance. As mentioned in our Welcome to Agents Week post, agents are one-to-one. Each agent is a unique instance, serving one user, running one task. A restaurant has a menu and a kitchen optimized to churn out dishes at volume. An agent is more like a personal chef: different ingredients, different techniques, different tools every time.

That fundamentally changes the scaling math. If a hundred million knowledge workers each use an agentic assistant at even modest concurrency, you need capacity for tens of millions of simultaneous sessions. At current per-container costs, that’s unsustainable. We need a different foundation.

That’s what we’ve been building.

Introducing Project Think

Project Think ships a set of new primitives for the Agents SDK:

  • Durable execution with fibers: crash recovery, checkpointing, automatic keepalive

  • Sub-agents: isolated child agents with their own SQLite and typed RPC

  • Persistent sessions: tree-structured messages, forking, compaction, full-text search

  • Sandboxed code execution: Dynamic Workers, codemode, runtime npm resolution

  • The execution ladder: workspace, isolate, npm, browser, sandbox

  • Self-authored extensions: agents that write their own tools at runtime

Each of these is usable directly with the Agent base class. Build exactly what you need with the primitives, or use the Think base class to get started fast. Let’s look at what each one does.

Long-running agents

Agents, as they exist today, are ephemeral. They run for a session, tied to a single process or device, and then they are gone. A coding agent that dies when your laptop sleeps, that’s a tool. An agent that persists — that can wake up on demand, continue work after interruptions, and carry forward the state without depending on your local runtime — that starts to look like infrastructure. And it changes the scaling model for agents completely.

The Agents SDK builds on Durable Objects to give every agent an identity, persistent state, and the ability to wake on message. This is the actor model: each agent is an addressable entity with its own SQLite database. It consumes zero compute when hibernated. When something happens (an HTTP request, a WebSocket message, a scheduled alarm, an inbound email) the platform wakes the agent, loads its state, and hands it the event. The agent does its work, then goes back to sleep.

VMs / Containers

Durable Objects

Idle cost

Full compute cost, always

Zero (hibernated)

Scaling

Provision and manage capacity

Automatic, per-agent

State

External database required

Built-in SQLite

Recovery

You build it (process managers, health checks)

Platform restarts, state survives

Identity / routing

You build it (load balancers, sticky sessions)

Built-in (name → agent)

10,000 agents, each active 1% of the time

10,000 always-on instances

~100 active at any moment

This changes the economics of running agents at scale. Instead of “one expensive agent per power user,” you can build “one agent per customer” or “one agent per task” or “one agent per email thread.” The marginal cost of spawning a new agent is effectively zero.

Surviving crashes: durable execution with fibers

An LLM call takes 30 seconds. A multi-turn agent loop can run for much longer. At any point during that window, the execution environment can vanish: a deploy, a platform restart, hitting resource limits. The upstream connection to the model provider is severed permanently, in-memory state is lost, and connected clients see the stream stop with no explanation.

runFiber() solves this. A fiber is a durable function invocation: registered in SQLite before execution begins, checkpointable at any point via stash(), and recoverable on restart via onFiberRecovered.

import { Agent } from "agents";

export class ResearchAgent extends Agent {
  async startResearch(topic: string) {
    void this.runFiber("research", async (ctx) => {
      const findings = [];

      for (let i = 0; i < 10; i++) {
        const result = await this.callLLM(`Research step ${i}: ${topic}`);
        findings.push(result);

        // Checkpoint: if evicted, we resume from here
        ctx.stash({ findings, step: i, topic });

        this.broadcast({ type: "progress", step: i });
      }

      return { findings };
    });
  }

  async onFiberRecovered(ctx) {
    if (ctx.name === "research" && ctx.snapshot) {
      const { topic } = ctx.snapshot;
      await this.startResearch(topic);
    }
  }
}

The SDK keeps the agent alive automatically during fiber execution, no special configuration needed. For work measured in minutes, keepAlive() / keepAliveWhile() prevents eviction during active work. For longer operations (CI pipelines, design reviews, video generation) the agent starts the work, persists the job ID, hibernates, and wakes on callback.

Delegating work: sub-agents via Facets

A single agent shouldn’t do everything itself. Sub-agents are child Durable Objects colocated with the parent via Facets, each with their own isolated SQLite and execution context:

import { Agent } from "agents";

export class ResearchAgent extends Agent {
  async search(query: string) { /* ... */ }
}

export class ReviewAgent extends Agent {
  async analyze(query: string) { /* ... */ }
}

export class Orchestrator extends Agent {
  async handleTask(task: string) {
    const researcher = await this.subAgent(ResearchAgent, "research");
    const reviewer = await this.subAgent(ReviewAgent, "review");

    const [research, review] = await Promise.all([
      researcher.search(task),
      reviewer.analyze(task)
    ]);

    return this.synthesize(research, review);
  }
}

Sub-agents are isolated at the storage level. Each one gets its own SQLite database, and there’s no implicit sharing of data between them. This is enforced by the runtime where sub-agent RPC latency is a function call. TypeScript catches misuse at compile time.

Conversations that persist: the Session API

Agents that run for days or weeks need more than the typical flat list of messages. The experimental Session API models this explicitly. Available on the Agent base class, conversations are stored as trees, where each message has a parent_id. This enables forking (explore an alternative without losing the original path), non-destructive compaction (summarize older messages rather than deleting them), and full-text search across conversation history via FTS5.

import { Agent } from "agents";
import { Session, SessionManager } from "agents/experimental/memory/session";

export class MyAgent extends Agent {
  sessions = SessionManager.create(this);

  async onStart() {
    const session = this.sessions.create("main");
    const history = session.getHistory();
    const forked = this.sessions.fork(session.id, messageId, "alternative-approach");
  }
}

Session is usable directly with Agent, and it’s the storage layer that the Think base class builds on.

From tool calls to code execution

Conventional tool-calling has an awkward shape. The model calls a tool, pulls the result back through the context window, calls another tool, pulls that back, and so on. As the tool surface grows, this gets both expensive and clumsy. A hundred files means a hundred round-trips through the model.

But models are better at writing code to use a system than they are at playing the tool-calling game. This is the insight behind @cloudflare/codemode: instead of sequential tool calls, the LLM writes a single program that handles the entire task.

// The LLM writes this. It runs in a sandboxed Dynamic Worker.
const files = await tools.find({ pattern: "**/*.ts" });
const results = [];
for (const file of files) {
  const content = await tools.read({ path: file });
  if (content.includes("TODO")) {
    results.push({ file, todos: content.match(/\/\/ TODO:.*/g) });
  }
}
return results;

Instead of 100 round-trips to the model, you just run a single program. This leads to fewer tokens used, faster execution, and better results. The Cloudflare API MCP server demonstrates this at scale. We expose only two tools (search() and execute()), which consume ~1,000 tokens, vs. ~1.17 million tokens for the naive tool-per-endpoint equivalent. This is a 99.9% reduction.

The missing primitive: safe sandboxes

Once you accept that models should write code on behalf of users, the question becomes: where does that code run? Not eventually, not after a product team turns it into a roadmap item. Right now, for this user, against this system, with tightly defined permissions.

Dynamic Workers are that sandbox. A fresh V8 isolate spun up at runtime, in milliseconds, with a few megabytes of memory. That’s roughly 100x faster and up to 100x more memory-efficient than a container. You can start a new one for every single request, run a snippet of code, and throw it away.

The critical design choice is the capability model. Instead of starting with a general-purpose machine and trying to constrain it, Dynamic Workers begin with almost no ambient authority (globalOutbound: null, no network access) and the developer grants capabilities explicitly, resource by resource, through bindings. We go from asking “how do we stop this thing from doing too much?” to “what exactly do we want this thing to be able to do?”

This is the right question for agent infrastructure.

The execution ladder

This capability model leads naturally to a spectrum of compute environments, an execution ladder that the agent escalates through as needed:


Tier 0 is the Workspace, a durable virtual filesystem backed by SQLite and R2. Read, write, edit, search, grep, diff. Powered by @cloudflare/shell.

Tier 1 is a Dynamic Worker: LLM-generated JavaScript running in a sandboxed isolate with no network access. Powered by @cloudflare/codemode.

Tier 2 adds npm. @cloudflare/worker-bundler fetches packages from the registry, bundles them with esbuild, and loads the result into the Dynamic Worker. The agent writes import { z } from "zod" and it just works.

Tier 3 is a headless browser via Cloudflare Browser Run. Navigate, click, extract, screenshot. Useful when the service doesn’t support agents yet via MCP or APIs.

Tier 4 is a Cloudflare Sandbox configured with your toolchains, repos, and dependencies: git clone, npm test, cargo build, synced bidirectionally with the Workspace.

The key design principle: the agent should be useful at Tier 0 alone, where each tier is additive. The user can add capabilities as they go.

Building blocks, not a framework

All of these primitives are available as standalone packages. Dynamic Workers, @cloudflare/codemode, @cloudflare/worker-bundler, and @cloudflare/shell (a durable filesystem with tools) are all usable directly with the Agent base class. You can combine them to give any agent a workspace, code execution, and runtime package resolution without adopting an opinionated framework.

The platform

Here’s the complete stack for building agents on Cloudflare:

Capability

What it does

Powered by

Per-agent isolation

Every agent is its own world

Durable Objects (DOs)

Zero cost when idle

$0 until the agent wakes up

DO Hibernation

Persistent state

Queryable, transactional storage

DO SQLite

Durable filesystem

Files that survive restarts

Workspace (SQLite + R2)

Sandboxed code execution

Run LLM-generated code safely

Dynamic Workers + @cloudflare/codemode

Runtime dependencies

import * from react just works

@cloudflare/worker-bundler

Web automation

Browse, navigate, fill forms

Browser Run

Full OS access

git, compilers, test runners

Sandboxes

Scheduled execution

Proactive, not just reactive

DO Alarms + Fibers

Real-time streaming

Token-by-token to any client

WebSockets

External tools

Connect to any tool server

MCP

Agent coordination

Typed RPC between agents

Sub-agents (Facets)

Model access

Connect to an LLM to power the agent

AI Gateway + Workers AI (or Bring Your Own Model)

Each of these is a building block. Together, they form something new: a platform where anyone can build, deploy, and run AI agents as capable as the ones running on your local machine today, but serverless, durable, and safe by construction.

The Think base class

Now that you’ve seen the primitives, here’s what happens when you wire them all together.

Think is an opinionated harness that handles the full chat lifecycle: agentic loop, message persistence, streaming, tool execution, stream resumption, and extensions. You focus on what makes your agent unique.

The minimal subclass looks like this:

import { Think } from "@cloudflare/think";
import { createWorkersAI } from "workers-ai-provider";

export class MyAgent extends Think<Env> {
  getModel() {
    return createWorkersAI({ binding: this.env.AI })(
      "@cf/moonshotai/kimi-k2.5"
    );
  }
}

That’s effectively all you need to have a working chat agent with streaming, persistence, abort/cancel, error handling, resumable streams, and a built-in workspace filesystem. Deploy with npx wrangler deploy.

Think makes decisions for you. When you need more control, you can override the ones you care about:

Override

Purpose

getModel()

Return the LanguageModel to use

getSystemPrompt()

System prompt

getTools()

AI SDK compatible ToolSet for the agentic loop

maxSteps

Max tool-call rounds per turn

configureSession()

Context blocks, compaction, search, skills

Under the hood, Think runs the complete agentic loop on every turn: it assembles the context (base instructions + tool descriptions + skills + memory + conversation history), calls streamText, executes tool calls (with output truncation to prevent context blowup), appends results, loops until the model is done or the step limit is reached. All messages are persisted after each turn.

Lifecycle hooks

Think gives you hooks at every stage of the chat turn, without requiring you to own the whole pipeline:

beforeTurn()
  → streamText()
    → beforeToolCall()
    → afterToolCall()
  → onStepFinish()
→ onChatResponse()

Switch to a lower cost model for follow-up turns, limit the tools it can use, and pass in client-side context on each turn. Also log every tool call to analytics and automatically trigger one more follow-up turn after the model completes, all without replacing onChatMessage.

Persistent memory and long conversations

Think builds on Session API as its storage layer, giving you tree-structured messages with branching built in.

On top of that, it adds persistent memory through context blocks. These are structured sections of the system prompt that the model can read and update over time, and they persist across hibernation.The model sees “MEMORY (Important facts, use set_context to update) [42%, 462/1100 tokens]” and can proactively remember things.

configureSession(session: Session) {
  return session
    .withContext("soul", {
      provider: { get: async () => "You are a helpful coding assistant." }
    })
    .withContext("memory", {
      description: "Important facts learned during conversation.",
      maxTokens: 2000
    })
    .withCachedPrompt();
}

Sessions are flexible. You can run multiple conversations per agent and fork them to try a different direction without losing the original. 

As context grows, Think handles limits with non-destructive compaction. Older messages are summarized instead of removed, while the full history remains stored in SQLite. 

Search is built in as well. Using FTS5, you can query conversation history within a session or across all the sessions. The agent is also able to search its own past using search_context tool.

The full execution ladder, wired in

Think integrates the entire execution ladder into a single getTools() return:

import { Think } from "@cloudflare/think";
import { createWorkspaceTools } from "@cloudflare/think/tools/workspace";
import { createExecuteTool } from "@cloudflare/think/tools/execute";
import { createBrowserTools } from "@cloudflare/think/tools/browser";
import { createSandboxTools } from "@cloudflare/think/tools/sandbox";
import { createExtensionTools } from "@cloudflare/think/tools/extensions";

export class MyAgent extends Think<Env> {
  extensionLoader = this.env.LOADER;

  getModel() {
    /* ... */
  }

  getTools() {
    return {
      execute: createExecuteTool({
        tools: createWorkspaceTools(this.workspace),
        loader: this.env.LOADER
      }),
      ...createBrowserTools(this.env.BROWSER),
      ...createSandboxTools(this.env.SANDBOX), // configured per-agent: toolchains, repos, snapshots
      ...createExtensionTools({ manager: this.extensionManager! }),
      ...this.extensionManager!.getTools()
    };
  }
}

Self-authored extensions

Think takes code execution one step further. An agent can write its own extensions: TypeScript programs that run in Dynamic Workers, declaring permissions for network access and workspace operations.

{
  "name": "github",
  "description": "GitHub integration: PRs, issues, repos",
  "tools": ["create_pr", "list_issues", "review_pr"],
  "permissions": {
    "network": ["api.github.com"],
    "workspace": "read-write"
  }
}

Think’s ExtensionManager bundles the extension (optionally with npm deps via @cloudflare/worker-bundler), loads it into a Dynamic Worker, and registers the new tools. The extension persists in DO storage and survives hibernation. The next time the user asks about pull requests, the agent has a github_create_pr tool that didn’t exist 30 seconds ago.

This is the kind of self-improvement loop that makes agents genuinely more useful over time. Not through fine-tuning or RLHF, but through code. The agent is able to write new capabilities for itself, all in sandboxed, auditable, and revocable TypeScript.

Sub-agent RPC

Think also works as a sub-agent, called via chat() over RPC from a parent, with streaming events via callback:

const researcher = await this.subAgent(ResearchSession, "research");
const result = await researcher.chat(`Research this: ${task}`, streamRelay);

Each child gets its own conversation tree, memory, tools, and model. The parent doesn’t need to know the details.

Getting started

Project Think is experimental. The API surface is stable but will continue to evolve in the coming days and weeks. We’re already using it internally to build our own background agent infrastructure, and we’re sharing it early so you can build alongside us.

npm install @cloudflare/think agents ai @cloudflare/shell zod workers-ai-provider
// src/server.ts
import { Think } from "@cloudflare/think";
import { createWorkersAI } from "workers-ai-provider";
import { routeAgentRequest } from "agents";

export class MyAgent extends Think<Env> {
  getModel() {
    return createWorkersAI({ binding: this.env.AI })(
      "@cf/moonshotai/kimi-k2.5"
    );
  }
}

export default {
  async fetch(request: Request, env: Env) {
    return (
      (await routeAgentRequest(request, env)) ||
      new Response("Not found", { status: 404 })
    );
  }
} satisfies ExportedHandler<Env>;
// src/client.tsx
import { useAgent } from "agents/react";
import { useAgentChat } from "@cloudflare/ai-chat/react";

function Chat() {
  const agent = useAgent({ agent: "MyAgent" });
  const { messages, sendMessage, status } = useAgentChat({ agent });
  // Render your chat UI
}

Think speaks the same WebSocket protocol as @cloudflare/ai-chat, so existing UI components work out of the box. If you’ve built on AIChatAgent, your client code doesn’t change.

The third wave

We see three waves of AI agents:

The first wave was chatbots. They were stateless, reactive, and fragile. Every conversation started from scratch with no memory, no tools, and no ability to act. This made them useful for answering questions, but limited them to only answering questions.

The second wave was coding agents. These are stateful, tool-using and far more capable tools like Pi, Claude Code, OpenClaw, and Codex. These agents can read codebases, write code, execute it, and iterate. These proved that an LLM with the right tools is a general-purpose machine, but they run on your laptop, for one user, with no durability guarantees.

Now we are entering the third wave: agents as infrastructure. Durable, distributed, structurally safe, and serverless. These are agents that run on the Internet, survive failures, cost nothing when idle, and enforce security through architecture rather than behavior. Agents that any developer can build and deploy for any number of users.

This is the direction we’re betting on.

The Agents SDK is already powering thousands of production agents. With Project Think and the the primitives it introduces, we’re adding the missing pieces to make those agents dramatically more capable: persistent workspaces, sandboxed code execution, durable long-running tasks, structural security, sub-agent coordination, and self-authored extensions.

It’s available today in preview. We’re building alongside you, and we’d genuinely love to see what you (and your coding agent) create with it.


Think is part of the Cloudflare Agents SDK, available as @cloudflare/think. The features described in this post are in preview. APIs may change as we incorporate feedback. Check the documentation and example to get started.


Register domains wherever you build: Cloudflare Registrar API now in beta

Post Syndicated from Ankit Shah original https://blog.cloudflare.com/registrar-api-beta/

Today we’re launching the next chapter of Cloudflare Registrar: the Registrar API in beta.

The Registrar API makes it possible to search for domains, check availability, and register them programmatically. Now, buying a domain the moment an idea starts to feel real no longer has to pull you out of the agentic workflow.

A Registrar API has been one of the clearest asks from builders using Cloudflare. As more of the agentic workflow has moved into editors, terminals, and agent-driven tools, domain registration became the obvious gap to close.

When we launched Cloudflare Registrar seven years ago, the idea was simple. Domains should be offered at cost, with no markup and no games. Since then, Cloudflare Registrar has become one of the fastest growing registrars in the world as more people choose Cloudflare as the place to build their next project.

Prompting an agent inside an AI code editor to generate name ideas, search, check, and purchase a domain.

Built for agents and automation

The Registrar API is designed to work well anywhere software is already being built: inside editors, deployment pipelines, backend services, and agent-driven workflows.

The workflow is intentionally simple and machine-friendly. Search returns candidate names. Check returns real-time availability and pricing. Register takes a minimal request and returns a workflow-shaped response that can complete immediately or be polled if it takes longer. That makes it straightforward to use for traditional API clients and for AI agents acting on a user’s behalf.

In practice, all this means that an agent can help with the full flow: suggest names, confirm which one is actually registrable, surface the price for approval, and then complete the purchase without forcing the user out of the tool they are already using.

The Registrar API

At its core, this first release of the Registrar API does three things

  • Search for domains

  • Check availability

  • Register domains

For a curated set of popular TLDs to start, see the Registrar API docs. When supported, premium domains can also be registered, but they require explicit fee acknowledgement.

The Registrar API is part of the full Cloudflare API, which means agents already have access to it today through the Cloudflare MCP. It does not require a separate integration or a custom tool definition. An agent working in Cursor, Claude Code, or any MCP-compatible environment can discover and call Registrar endpoints using the same search() and execute() pattern that covers the entire Cloudflare API surface. The moment the API was part of our spec, it was ready for agents.

What it looks like in practice:

You’re building a new project in your favorite AI code editor. Halfway through scaffolding, you ask your agent: “Find me a good .dev domain for this project and register it.”

The agent searches for candidate names based on your project. It checks real-time availability for the one you pick and confirms the price. You say yes. It registers the domain, using your account’s default contact info and payment method automatically. By the time you’ve read the response, the domain is registered, and privacy is on.

Three API calls. A few seconds.

What it looks like in code:

Step 1: Search for domain names

Use the search endpoint to submit a domain query, with or without a domain extension.

async () => {
  return cloudflare.request({
    method: "GET",
    path: `/accounts/${accountId}/registrar/domain-search`,
    query: { q: "acme corp", limit: 3 },
  });
}
{
  "success": true,
  "errors": [],
  "messages": [],
  "result": {
    "domains": [
      {
        "name": "acmecorp.com",
        "registrable": true,
        "tier": "standard",
        "pricing": {
          "currency": "USD",
          "registration_cost": "8.57",
          "renewal_cost": "8.57"
        }
      },
      {
        "name": "acmecorp.dev",
        "registrable": true,
        "tier": "standard",
        "pricing": {
          "currency": "USD",
          "registration_cost": "10.11",
          "renewal_cost": "10.11"
        }
      },
      {
        "name": "acmecorp.app",
        "registrable": true,
        "tier": "standard",
        "pricing": {
          "currency": "USD",
          "registration_cost": "11.00",
          "renewal_cost": "11.00"
        }
      }
    ]
  }
}

Step 2: Check availability and pricing

Search results are fast but non-authoritative; they’re based on cached data, and availability can change in seconds for popular names. Check queries the registry directly. Call it immediately before registering, and use its price response as the source of truth.

async () => {
  return cloudflare.request({
    method: "POST",
    path: `/accounts/${accountId}/registrar/domain-check`,
    body: { domains: ["acmecorp.dev"] },
  });
}
{
  "success": true,
  "errors": [],
  "messages": [],
  "result": {
    "domains": [
      {
        "name": "acmecorp.dev",
        "registrable": true,
        "tier": "standard",
        "pricing": {
          "currency": "USD",
          "registration_cost": "10.11",
          "renewal_cost": "10.11"
        }
      }
    ]
  }
}

Step 3: Register the domain

The only required field is the domain name. WHOIS privacy protection is enabled by default at no extra charge. If your account has a default registrant contact, the API uses it automatically; otherwise you can provide contact details inline in the request. Your default payment method is used automatically.

async () => {
  return cloudflare.request({
    method: "POST",
    path: `/accounts/${accountId}/registrar/registrations`,
    body: { domain_name: "acmecorp.dev" },
  });
}
{
  "success": true,
  "errors": [],
  "messages": [],
  "result": {
    "domain_name": "acmecorp.dev",
    "state": "succeeded",
    "completed": true,
    "created_at": "2025-10-27T10:00:00Z",
    "updated_at": "2025-10-27T10:00:03Z",
    "context": {
      "registration": {
        "domain_name": "acmecorp.dev",
        "status": "active",
        "created_at": "2025-10-27T10:00:00Z",
        "expires_at": "2026-10-27T10:00:00Z",
        "auto_renew": true,
        "privacy_enabled": true,
        "locked": true
      }
    },
    "links": {
      "self": "/accounts/abc/registrar/registrations/acmecorp.dev/registration-status",
      "resource": "/accounts/abc/registrar/registrations/acmecorp.dev"
    }
  }
}

Registration typically completes synchronously within seconds. If it takes longer, the API returns a 202 Accepted with a workflow URL to poll. The response shape is the same either way, no special-casing needed. For premium domains, the Check response returns the exact registry-set price, and the Register request echoes that back as an explicit fee acknowledgement.

A note on agents and non-refundable purchases

When an agent registers a domain on your behalf, it charges your default payment method. Domain registrations are non-refundable once complete. A well-designed agent flow should confirm the domain name and price with the user before calling the registration endpoint. The Check step exists precisely to make that confirmation step explicit and unambiguous. The API gives you the tools to build it correctly; the responsibility to do so belongs in your agent’s logic.

By default, our API docs have explicit agent-facing instructions to seek permission from the user during the register API call. Still, it is the responsibility of the human to design an agent flow that will not buy domains without your approval.

Why Cloudflare can do this differently

What makes Cloudflare different from many developer platforms now adding domain workflows is that Cloudflare operates the registrar itself. That means the same platform where a project is built and deployed can also search for, register, and manage the domain — without adding markup on top.

At-cost pricing is at the core of Cloudflare’s registrar model. We charge exactly what the registry charges. That holds true whether you’re registering a domain through the dashboard, calling the API directly, or asking an agent to do it on your behalf.

Where the API goes next

This beta focuses on the first critical moment in the domain lifecycle: search, check, and registration. We are actively working on expanding the API to cover more of the core Registrar experience, so domains can be managed programmatically after they are purchased, not just at the moment they are created. This will include lifecycle elements like transfers, renewals, contact updates, and more.

The API is the first step toward a broader registrar-as-a-service offering. Development of that service is underway now, and we’re aiming to launch it later this year. As the API expands, platforms like website builders, hosting providers, AI products, and other multi-tenant applications will be able to make domain registration part of their own user experience. Users can search for a domain, buy it, and provision it without ever leaving the service or agent-driven workflow they are already building in.

Start building today

The Registrar API exists because builders asked for it. Now that it’s available as a beta, we’d love to see what you build, in the Cloudflare Community or on X, or on Discord.

To get started:

Please let us know if something is missing, if a workflow breaks down, or if you are building toward a larger platform use case. We’re working quickly to expand the functionality of the API to support domain renewals, transfers, and more.

We can’t wait to see what you build!

Special thanks to Lucy Dryaeva and Fred Pinto for their valuable contributions to delivering the Registrar API beta.

Introducing Agent Lee – a new interface to the Cloudflare stack

Post Syndicated from Kylie Czajkowski original https://blog.cloudflare.com/introducing-agent-lee/

While there have been small improvements along the way, the interface of technical products has not really changed since the dawn of the Internet. It still remains: clicking five pages deep, cross-referencing logs across tabs, and hunting for hidden toggles.

AI gives us the opportunity to rethink all that. Instead of complexity spread over a sprawling graphical user interface: what if you could describe in plain language what you wanted to achieve? 

This is the future — and we’re launching it today. We didn’t want to just put an agent in a dashboard. We wanted to create an entirely new way to interact with our entire platform. Any task, any surface, a single prompt.
Introducing Agent Lee.

Agent Lee is an in-dashboard AI assistant that understands your Cloudflare account. 

It can help you with troubleshooting, which, today, is a manual grind. If your Worker starts returning 503s at 02:00 UTC, finding the root cause: be it an R2 bucket, a misconfigured route, or a hidden rate limit, you’re opening half a dozen tabs and hoping you recognize the pattern. Most developers don’t have a teammate who knows the entire platform standing over their shoulder at 2 a.m. Agent Lee does. 

But it won’t just troubleshoot for you at 2 a.m. Agent Lee will also fix the problem for you on the spot.


Agent Lee has been running in an active beta during which it has served over 18,000 daily users, executing nearly a quarter of a million tool calls per day. While we are confident in its current capabilities and success in production, this is a system we are continuously developing. As it remains in beta, you may encounter unexpected limitations or edge cases as we refine its performance. We encourage you to use the feedback form below to help us make it better every day.

What Agent Lee can do

Agent Lee is built directly into the dashboard and understands the resources in your account. It knows your Workers, your zones, your DNS configuration, your error rates. The knowledge that today lives across six tabs and two browser windows will now live in one place, and you can talk to it.

With natural language, you can use it to:

  • Answer questions about your account: “Show me the top 5 error messages on my Worker.”

  • Debug an issue: “I can’t access my site with the www prefix.”

  • Apply a change: “Enable Access for my domain.”

  • Deploy a resource: “Create a new R2 bucket for my photos and connect it to my Worker.”

Instead of switching between products, you describe what you want to do, and Agent Lee helps you get there with instructions and visualizations. It retrieves context, uses the right tools, and creates dynamic visualizations based on the types of questions you ask. Ask what your error rate looks like over the last 24 hours, and it renders a chart inline, pulling from your actual traffic, not sending you to a separate Analytics page.

Agent Lee isn’t answering FAQ questions — it’s doing real work, against real accounts, at scale. Today, Agent Lee serves ~18,000 daily users, executing ~250k tool calls per day across DNS, Workers, SSL/TLS, R2, Registrar, Cache, Cloudflare Tunnel, API Shield, and more. 

How we built it

Codemode

Rather than presenting MCP tool definitions directly to the model, Agent Lee uses Codemode to convert the tools into a TypeScript API and asks the model to write code that calls it instead.

This works better for a couple of reasons. LLMs have seen a huge amount of real-world TypeScript but very few tool call examples, so they’re more accurate when working in code. For multi-step tasks, the model can also chain calls together in a single script and return only the final result, ultimately skipping the round-trips.

The generated code is sent to an upstream Cloudflare MCP server for sandboxed execution, but it goes through a Durable Object that acts as a credentialed proxy. Before any call goes out, the DO classifies the generated code as read or write by inspecting the method and body. Read operations are proxied directly. Write operations are blocked until you explicitly approve them through the elicitation gate. API keys are never present in the generated code — they’re held inside the DO and injected server-side when the upstream call is made. The security boundary isn’t just a sandbox that gets thrown away; it’s a permission architecture that structurally prevents writes from happening without your approval.

The MCP permission system

Agent Lee connects to Cloudflare’s own MCP server, which exposes two tools: a search tool for querying API endpoints and an execute tool for writing code that performs API requests. This is the surface through which Agent Lee reads your account and, when you approve, writes to it.

Write operations go through an elicitation system that surfaces the approval step before any code executes. Agent Lee cannot skip this step. The permission model is the enforcement layer, and the confirmation prompt you see is not a UX courtesy. It’s the gate.


Built on the same stack you can use

Every primitive Agent Lee is built on is available to all our customers: Agents SDK, Workers AI, Durable Objects, and the same MCP infrastructure available to any Cloudflare developer. We didn’t build internal tools that aren’t available to you — instead we built it with the same Cloudflare lego blocks that you have access to.

Building Agent Lee on our own primitives wasn’t just a design principle. It was the fastest way to find out what works and what doesn’t. We built this in production, with real users, against real accounts. That means every limitation we hit is a limitation we can fix in the platform. Every pattern that works is one we can make easier for the next team that builds on top of it.

These are not opinions. They’re what quarter of a million tool calls across 18,000 users a day are telling us.


Generative UI

Interacting with a platform should feel like collaborating with an expert. Conversations should transcend simple text. With Agent Lee, as your dialogue evolves, the platform dynamically generates UI components alongside textual responses to provide a richer, more actionable experience.

For example, if you ask about website traffic trends for the month, you won’t just get a paragraph of numbers. Agent Lee will render an interactive line graph, allowing you to visualize peaks and troughs in activity at a glance.

To give you full creative control, every conversation is accompanied within an adaptive grid. Here you can click and drag across the grid to carve out space for new UI blocks, then simply describe what you want to see and let the agent handle the heavy lifting.

Today, we support a diverse library of visual blocks, including dynamic tables, interactive charts, architecture maps, and more. By blending the flexibility of natural language with the clarity of structured UI, Agent Lee transforms your chat history into a living dashboard.


Measuring quality and safety

An agent that can take action on your account needs to be reliable and secure. Elicitations allow agentic systems to actively solicit information, preferences, or approvals from users or other systems mid-execution. When Agent Lee needs to take non-read actions on a user’s behalf we use elicitations by requiring an explicit approval action in the user interface. These guardrails allow Agent Lee to truly be a partner alongside you in managing your resource safely.

In addition to safety, we continuously measure quality.

  • Evals to measure conversation success rate and information accuracy.

  • Feedback signals from user interactions (thumbs up / thumbs down).

  • Tool call execution success rate and hallucination scorers.

  • Per-product breakdown of conversation performance.

These systems help us improve Agent Lee over time while keeping users in control. 

Our vision ahead

Agent Lee in the dashboard is only the beginning.

The bigger vision is Agent Lee as the interface to the entire Cloudflare platform — from anywhere. The dashboard today, the CLI next, your phone when you’re on the go. The surface you use shouldn’t matter. You should be able to describe what you need and have it done, regardless of where you are.

From there, Agent Lee gets proactive. Rather than waiting to be asked, it watches what matters to you, your Workers, your traffic, your error thresholds and reaches out when something warrants attention. An agent that only responds is useful. One that notices things first is something different.

Underlying all of this is context. Agent Lee already knows your account configuration. Over time, it will know more, what you’ve asked before, what page you’re on, what you were debugging last week. That accumulated context is what makes a platform feel less like a tool and more like a collaborator.

We’re not there yet. Agent Lee today is the first step, running in production, doing real work at scale. The architecture is built to get to the rest.

Try it out

Agent Lee is available in beta for Free plan users. Log in to your Cloudflare dashboard and click Ask AI in the upper right corner to get started.


We’d love to know what you build and what you’d like to see in Agent Lee. Please share your feedback here.


Securing non-human identities: automated revocation, OAuth, and scoped permissions

Post Syndicated from Justin Hutchings original https://blog.cloudflare.com/improved-developer-security/

Agents let you build software faster than ever, but securing your environment and the code you write — from both mistakes and malice — takes real effort. Open Web Application Security Project (OWASP) details a number of risks present in agentic AI systems, including the risk of credential leaks, user impersonation, and elevation of privilege. These risks can result in extreme damage to your environments including denial of service, data loss, or data leaks — which can do untold financial and reputational damage. 

This is an identity problem. In modern development, “identities” aren’t just people — they are the agents, scripts, and third-party tools that act on your behalf. To secure these non-human identities, you need to manage their entire lifecycle: ensuring their credentials (tokens) aren’t leaked, seeing which applications have access via OAuth, and narrowing their permissions using granular RBAC.

Today, we are introducing updates to address these needs: scannable tokens to protect your credentials, OAuth visibility to manage your principals, and resource-scoped RBAC to fine-tune your policies.

Understanding identity: Principals, Credentials, and Policies

To secure the Internet in an era of autonomous agents, we have to rethink how we handle identity. Whether a request comes from a human developer or an AI agent, every interaction with an API relies on three core pillars:

  • The Principal (The Traveler): This is the identity itself — the “who.” It might be you logging in via OAuth, or a background agent using an API token to deploy code.

  • The Credential (The Passport): This is the proof of that identity. In this world, your API token is your passport. If it’s stolen or leaked, anyone can “wear” your identity.

  • The Policy (The Visa): This defines what that identity is allowed to do. Just because you have a valid passport doesn’t mean you have a visa to enter every country. A policy ensures that even a verified identity can only access the specific resources it needs.

When these three pillars aren’t managed together, security breaks down. You might have a valid Principal using a stolen Credential, or a legitimate identity with a Policy that is far too broad.

Leaked token detection

Agents and other third-party applications use API tokens to access the Cloudflare API. One of the simplest ways that we see people leaking their secrets is by accidentally pushing them to a public GitHub repository. GitGuardian reports that last year more than 28 million secrets were published to public GitHub repositories, and that AI is causing leaks to happen 5x faster than before.

If an API token is a digital passport, then leaking it on a public repository is like leaving your passport on a park bench. Anyone who finds it can impersonate that identity until the document is canceled. Our partnership with GitHub acts like a global “lost and found” for these credentials. By the time you realize your passport is missing, we’ve already identified the document, verified its authenticity via the checksum, and voided it to prevent misuse.

We’re partnering with several leading credential scanning tools to help proactively find your leaked tokens and revoke them before they could be used maliciously. We know it’s not a matter of if, but rather when, before you, an employee, or one of your agents makes a mistake and pushes a secret somewhere it shouldn’t be. 

GitHub

We’ve partnered with GitHub and are participating in their Secret Scanning program to find your tokens in both public and private repositories. If we are notified that a token has leaked to a public repository, we will automatically revoke the token to prevent it from being used maliciously. For private repositories, GitHub will notify you about any leaked Cloudflare tokens and you can clean these up.

How it works

We’ve shared the new token formats (below!) with GitHub, and they now scan for them on every commit. If they find something that looks like a leaked Cloudflare token, they verify the token is real (using the checksum), send us a webhook to revoke it, and then we notify you via email so you can generate a new one in Dashboard settings.

This means we plug the hole as soon as it’s found. By the time you realize you made a mistake, we’ve already fixed it. 

We hope this is the kind of feature you don’t need to use, but our partners are on the lookout for leaks to help keep you secure. 

Cloudflare One

Cloudflare One customers are also protected from these leaks. By configuring the Credentials and Secrets DLP profile, organizations can activate prevention everywhere a credential can travel:

  • Network Traffic (Cloudflare Gateway): Apply these entries to a policy to detect and block Cloudflare API tokens moving across your network. A token in a file upload, an outbound request, or a download is stopped before it reaches its destination.

  • Outbound Email (Cloudflare Email Security): Microsoft 365 customers can extend this same prevention to Outlook. The DLP Assist add-in scans messages before delivery, catching a token before it’s sent externally.

  • Data at Rest (Cloudflare CASB): Cloudflare’s Cloud Access Security Broker applies the same profile to scan files across connected SaaS applications, catching tokens saved or shared in Google Drive, OneDrive, Dropbox, and other integrated services.

The most novel exposure vector, though, is AI traffic. Cloudflare AI Gateway integrates with the same DLP profiles to scan and block both incoming prompts and outgoing AI model responses in real time.

Other credential scanners

The only way credential scanning works is if we meet you where you are, so we are working with several open source and commercial credential scanners to ensure you are protected no matter what secret scanner you use. 

How it works

Until now, Cloudflare’s API tokens were pretty generic looking, so they were hard for credential scanners to identify with high confidence. These automated security tools scan your code repositories looking for exposed credentials like API keys, tokens or passwords. The “cf” prefix makes Cloudflare tokens instantly recognizable with greater confidence, and the checksum makes it easy for tools to statically validate them. Your existing tokens will continue to work, but every new token you generate will use the scannable format so it’s easily detected with high confidence.

Credential Type

What it’s for

New Format

User API Key

Legacy global API key tied to your user account (full access)

cfk_[40 characters][checksum]

User API Token

Scoped token you create for specific permissions

cfut_[40 characters][checksum]

Account API Token

Token owned by the account (not a specific user)

cfat_[40 characters][checksum]

Getting started

If you have existing API tokens, you can roll the token to create a new, scannable API token. This is optional, but recommended to ensure that your tokens are easily discoverable in case they leak. 

While API tokens are generally used by your own scripts and agents, OAuth is how you manage access for third-party platforms. Both require clear visibility to prevent unauthorized access and ensure you know exactly who — or what — has access to your data.

Improving the OAuth consent experience

When you connect third-party applications like Wrangler to your Cloudflare Account using OAuth, you’re granting that application access to your account’s data. Over time, you may forget why you granted a third party application access to your Account in the first place. Previously, there was no central place to view & manage those applications. Starting today, there is.  

Going forward, when a third party application requests access to your Cloudflare account, you’ll be able to review: 

  • Which third-party application is requesting access, along with information about the application like Name, Logo, and the Publisher.

  • Which scopes the third-party application is requesting access to.

  • Which accounts to grant the third party application access to.

Before After

Not all applications require the same permissions; some only need to read data, others may need to make changes to your Account. Understanding these scopes before you grant access helps you maintain least-privilege.

We also added a Connected Applications experience so you can see which applications have access to which accounts, what scopes/permissions are associated with that application, and easily revoke that access as needed. 


Getting started

The OAuth consent and revocation improvements are available now. Check which apps currently have access to your accounts by visiting My Profile > Access Management > Connected Applications. 

For developers building integrations with Cloudflare, keep an eye on the Cloudflare Changelog for more announcements around how you can register your own OAuth apps soon! 

Fine-grained resource-level permissioning 

If the token is the passport, then resource-scoped permissions are the visas inside it. Having a valid passport gets you through the front door, but it shouldn’t give you access to every room in the building. By narrowing the scope to specific resources — like a single Load Balancer pool or a specific Gateway policy — you are ensuring that even if an identity is verified, it only has the “visa” to go where it’s strictly necessary.

Last year, we announced support for resource scoped permissions in Cloudflare’s role-based access control (RBAC) system for several of our Zero Trust products. This enables you to right size permissions for both users and agents to minimize security risks. We’ve expanded this capability to several new resources-level permissions. The resource scope is now supported for:

  • Access Applications

  • Access Identity Providers

  • Access Policies

  • Access Service Tokens

  • Access Targets

We’ve also completely overhauled the API Token creation experience, making it easier for customers to provision and manage Account API Tokens right from the Cloudflare Dashboard.


How it works

When you add a member to your Cloudflare account or create an API Token, you typically assign that principal a policy. A Permission Policy is what gives a principal permission to take an action, whether that’s managing Cloudflare One Access Applications, or DNS Records. Without a policy, a principal can authenticate, but they are unauthorized to do any actions within an account.

Policies are made up of three components: a Principal, a Role, and a Scope. The Principal is who or what you’re granting access to, whether that’s a human user, a Non-Human Identity (NHI) like an API Token, or increasingly, an Agent acting on behalf of a user. The Role defines what actions they’re permitted to take. The Scope determines where those permissions apply, and historically, that’s been restricted to the entire account, or individual zones.

New permission roles

We’re also expanding the role surface more broadly at both the Account & Zone level with the introduction of a number of new roles for many products. 

  • Account scope

    • CDN Management

    • MCP Portals

    • Radar

    • Request Tracer

    • SSL/TLS Management

  • Zone scope

    • Analytics

    • Logpush

    • Page Rules

    • Security Center

    • Snippets

    • Zone Settings

Getting started

The resource scope and all new account and zone-level roles are available today for all Cloudflare customers. You can assign account, zone, or resource-scoped policies through the Cloudflare Dashboard, the API, or Terraform. 

For a full breakdown of all available roles and how scopes work, visit our roles and scope documentation.

Secure your accounts

These updates provide the granular building blocks needed for a true least-privilege architecture. By refining how we manage permissions and credentials, developers and enterprises can have greater confidence in their security posture across the users, apps, agents, and scripts that access Cloudflare. Least privilege isn’t a new concept, and for enterprises, it’s never been optional. Whether a human administrator is managing a zone or an agent is programmatically deploying a Worker, the expectation is the same, they should only be authorized to do the job it was given, and nothing else. 

Following today’s announcement, we recommend customers:

  1. Review your API tokens, and reissue with the new, scannable API tokens as soon as possible. 

  2. Review your authorized OAuth apps, and revoke any that you are no longer using

  3. Review member & API Token permissions in your accounts and ensure that users are taking advantage of the new account, zone, or resource scoped permissions as needed to reduce your risk area. 

Managed OAuth for Access: make internal apps agent-ready in one click

Post Syndicated from Eduardo Gomes original https://blog.cloudflare.com/managed-oauth-for-access/

We have thousands of internal apps at Cloudflare. Some are things we’ve built ourselves, others are self-hosted instances of software built by others. They range from business-critical apps nearly every person uses, to side projects and prototypes.

All of these apps are protected by Cloudflare Access. But when we started using and building agents — particularly for uses beyond writing code — we hit a wall. People could access apps behind Access, but their agents couldn’t.

Access sits in front of internal apps. You define a policy, and then Access will send unauthenticated users to a login page to choose how to authenticate. 


Example of a Cloudflare Access login page

This flow worked great for humans. But all agents could see was a redirect to a login page that they couldn’t act on.

Providing agents with access to internal app data is so vital that we immediately implemented a stopgap for our own internal use. We modified OpenCode’s web fetch tool such that for specific domains, it triggered the cloudflared CLI to open an authorization flow to fetch a JWT (JSON Web Token). By appending this token to requests, we enabled secure, immediate access to our internal ecosystem.

While this solution was a temporary answer to our own dilemma, today we’re retiring this workaround and fixing this problem for everyone. Now in open beta, every Access application supports managed OAuth. One click to enable it for an Access app, and agents that speak OAuth 2.0 can easily discover how to authenticate (RFC 9728), send the user through the auth flow, and receive back an authorization token (the same JWT from our initial solution). 

Now, the flow works smoothly for both humans and agents. Cloudflare Access has a generous free tier. And building off our newly-introduced Organizations beta, you’ll soon be able to bridge identity providers across Cloudflare accounts too.

How managed OAuth works

For a given internal app protected by Cloudflare Access, you enable managed OAuth in one click:


Once managed OAuth is enabled, Cloudflare Access acts as the authorization server. It returns the www-authenticate header, telling unauthorized agents where to look up information on how to get an authorization token. They find this at https://<your-app-domain>/.well-known/oauth-authorization-server. Equipped with that direction, agents can just follow OAuth standards: 

  1. The agent dynamically registers itself as a client (a process known as Dynamic Client Registration — RFC 7591), 

  2. The agent sends the human through a PKCE (Proof Key for Code Exchange) authorization flow (RFC 7636)

  3. The human authorizes access, which grants a token to the agent that it can use to make authenticated requests on behalf of the user

Here’s what the authorization flow looks like:


If this authorization flow looks familiar, that’s because it’s what the Model Context Protocol (MCP) uses. We originally built support for this into our MCP server portals product, which proxies and controls access to many MCP servers, to allow the portal to act as the OAuth server. Now, we’re bringing this to all Access apps so agents can access not only MCP servers that require authorization, but also web pages, web apps, and REST APIs.

Mass upgrading your internal apps to be agent-ready

Upgrading the long tail of internal software to work with agents is a daunting task. In principle, in order to be agent-ready, every internal and external app would ideally have discoverable APIs, a CLI, a well-crafted MCP server, and have adopted the many emerging agent standards.

AI adoption is not something that can wait for everything to be retrofitted. Most organizations have a significant backlog of apps built over many years. And many internal “apps” work great when treated by agents as simple websites. For something like an internal wiki, all you really need is to enable Markdown for Agents, turn on managed OAuth, and agents have what they need to read protected content.

To make the basics work across the widest set of internal applications, we use Managed OAuth. By putting Access in front of your legacy internal apps, you make them agent-ready instantly. No code changes, no retrofitting. Instead, just immediate compatibility.

It’s the user’s agent. No service accounts and tokens needed

Agents need to act on behalf of users inside organizations. One of the biggest anti-patterns we’ve seen is people provisioning service accounts for their agents and MCP servers, authenticated using static credentials. These have their place in simple use cases and quick prototypes, and Cloudflare Access supports service tokens for this purpose.

But the service account approach quickly shows its limits when fine-grained access controls and audit logs are required. We believe that every action an agent performs must be easily attributable to the human who initiated it, and that an agent must only be able to perform actions that its human operator is likewise authorized to do. Service accounts and static credentials become points at which attribution is lost. Agents that launder all of their actions through a service account are susceptible to confused deputy problems and result in audit logs that appear to originate from the agent itself.

For security and accountability, agents must use security primitives capable of expressing this user–agent relationship. OAuth is the industry standard protocol for requesting and delegating access to third parties. It gives agents a way to talk to your APIs on behalf of the user, with a token scoped to the user’s identity, so that access controls correctly apply and audit logs correctly attribute actions to the end user.

Standards for the win: how agents can and should adopt RFC 9728 in their web fetch tools

RFC 9728 is the OAuth standard that makes it possible for agents to discover where and how to authenticate. It standardizes where this information lives and how it’s structured. This RFC became official in April 2025 and was quickly adopted by the Model Context Protocol (MCP), which now requires that both MCP servers and clients support it.

But outside of MCP, agents should adopt RFC 9728 for an even more essential use case: making requests to web pages that are protected behind OAuth and making requests to plain old REST APIs.

Most agents have a tool for making basic HTTP requests to web pages. This is commonly called the “web fetch” tool. It’s similar to using the fetch() API in JavaScript, often with some additional post-processing on the response. It’s what lets you paste a URL into your agent and have your agent go look up the content.

Today, most agents’ web fetch tools won’t do anything with the www-authenticate header that a URL returns. The underlying model might choose to introspect the response headers and figure this out on its own, but the tool itself does not follow www-authenticate, look up /.well-known/oauth-authorization-server, and act as the client in the OAuth flow. But it can, and we strongly believe it should! Agents already do this to act as remote MCP clients.

To demonstrate this, we’ve put up a draft pull request that adapts the web fetch tool in Opencode to show this in action. Before making a request, the adapted tool first checks whether it already has credentials ; if it does, it uses them to make the initial request. If the tool gets back a 401 or a 403 with a www-authenticate header, it asks the user for consent to be sent through the server’s OAuth flow.

Here’s how that OAuth flow works. If you give the agent a URL that is protected by OAuth and complies with RFC 9728, the agent prompts the human for consent to open the authorization flow:


…sending the human to the login page:


…and then to a consent dialog that prompts the human to grant access to the agent:


Once the human grants access to the agent, the agent uses the token it has received to make an authenticated request:


Any agent from Codex to Claude Code to Goose and beyond can implement this, and there’s nothing bespoke to Cloudflare. It’s all built using OAuth standards.

We think this flow is powerful, and that supporting RFC 9728 can help agents with more than just making basic web fetch requests. If a REST API supports RFC 9728 (and the agent does too), the agent has everything it needs to start making authenticated requests against that API. If the REST API supports RFC 9727, then the client can discover a catalog of REST API endpoints on its own, and do even more without additional documentation, agent skills, MCP servers or CLIs. 

Each of these play important roles with agents — Cloudflare itself provides an MCP server for the Cloudflare API (built using Code Mode), Wrangler CLI, and Agent Skills, and a Plugin. But supporting RFC 9728 helps ensure that even when none of these are preinstalled, agents have a clear path forward. If the agent has a sandbox to execute untrusted code, it can just write and execute code that calls the API that the human has granted it access to. We’re working on supporting this for Cloudflare’s own APIs, to help your agents understand how to use Cloudflare.

Coming soon: share one identity provider (IdP) across many Cloudflare accounts

At Cloudflare our own internal apps are deployed to dozens of different Cloudflare accounts, which are all part of an Organization — a newly introduced way for administrators to manage users, configurations, and view analytics across many Cloudflare accounts. We have had the same challenge as many of our customers: each Cloudflare account has to separately configure an IdP, so Cloudflare Access uses our identity provider. It’s critical that this is consistent across an organization — you don’t want one Cloudflare account to inadvertently allow people to sign in just with a one-time PIN, rather than requiring that they authenticate via single-sign on (SSO).

To solve this, we’re currently working on making it possible to share an identity provider across Cloudflare accounts, giving organizations a way to designate a single primary IdP for use across every account in their organization.

As new Cloudflare accounts are created within an organization, administrators will be able to configure a bridge to the primary IdP with a single click, so Access applications across accounts can be protected by one identity provider. This removes the need to manually configure IdPs account by account, which is a process that doesn’t scale for organizations with many teams and individuals each operating their own accounts.

What’s next

Across companies, people in every role and business function are now using agents to build internal apps, and expect their agents to be able to access context from internal apps. We are responding to this step function growth in internal software development by making the Workers Platform and Cloudflare One work better together — so that it is easier to build and secure internal apps on Cloudflare. 

Expect more to come soon, including:

  • More direct integration between Cloudflare Access and Cloudflare Workers, without the need to validate JWTs or remember which of many routes a particular Worker is exposed on.

  • wrangler dev –tunnel — an easy way to expose your local development server to others when you’re building something new, and want to share it with others before deploying

  • A CLI interface for Cloudflare Access and the entire Cloudflare API

  • More announcements to come during Agents Week 2026

Enable Managed OAuth for your internal apps behind Cloudflare Access

Managed OAuth is now available, in open beta, to all Cloudflare customers. Head over to the Cloudflare dashboard to enable it for your Access applications. You can use it for any internal app, whether it’s one built on Cloudflare Workers, or hosted elsewhere. And if you haven’t built internal apps on the Workers Platform yet — it’s the fastest way for your team to go from zero to deployed (and protected) in production.

Agents have their own computers with Sandboxes GA

Post Syndicated from Kate Reznykova original https://blog.cloudflare.com/sandbox-ga/

When we launched Cloudflare Sandboxes last June, the premise was simple: AI agents need to develop and run code, and they need to do it somewhere safe.

If an agent is acting like a developer, this means cloning repositories, building code in many languages, running development servers, etc. To do these things effectively, they will often need a full computer (and if they don’t, they can reach for something lightweight!).

Many developers are stitching together solutions using VMs or existing container solutions, but there are lots of hard problems to solve:

  • Burstiness – With each session needing its own sandbox, you often need to spin up many sandboxes quickly, but you don’t want to pay for idle compute on standby.

  • Quick state restoration – Each session should start quickly and re-start quickly, resuming past state.

  • Security – Agents need to access services securely, but can’t be trusted with credentials.

  • Control – It needs to be simple to programmatically control sandbox lifecycle, execute commands, handle files, and more.

  • Ergonomics – You need to give a simple interface for both humans and agents to do common operations.

We’ve spent time solving these issues so you don’t have to. Since our initial launch we’ve made Sandboxes an even better place to run agents at scale. We’ve worked with our initial partners such as Figma, who run agents in containers with Figma Make:

“Figma Make is built to help builders and makers of all backgrounds go from idea to production, faster. To deliver on that goal, we needed an infrastructure solution that could provide reliable, highly-scalable sandboxes where we could run untrusted agent- and user-authored code. Cloudflare Containers is that solution.”

Alex Mullans, AI and Developer Platforms at Figma

We want to bring Sandboxes to even more great organizations, so today we are excited to announce that Sandboxes and Cloudflare Containers are both generally available.

Let’s take a look at some of the recent changes to Sandboxes:

  • Secure credential injection lets you make authenticated calls without the agent ever having credential access  

  • PTY support gives you and your agent a real terminal

  • Persistent code interpreters give your agent a place to execute stateful Python, JavaScript, and TypeScript out of the box

  • Background processes and live preview URLs provide a simple way to interact with development servers and verify in-flight changes

  • Filesystem watching improves iteration speed as agents make changes

  • Snapshots let you quickly recover an agent’s coding session

  • Higher limits and Active CPU Pricing let you deploy a fleet of agents at scale without paying for unused CPU cycles

Sandboxes 101

Before getting into some of the recent changes, let’s quickly look at the basics.

A Cloudflare Sandbox is a persistent, isolated environment powered by Cloudflare Containers. You ask for a sandbox by name. If it’s running, you get it. If it’s not, it starts. When it’s idle, it sleeps automatically and wakes when it receives a request. It’s easy to programmatically interact with the sandbox using methods like exec, gitClone, writeFile and more.

import { getSandbox } from "@cloudflare/sandbox";
export { Sandbox } from "@cloudflare/sandbox";

export default {
  async fetch(request: Request, env: Env) {
    // Ask for a sandbox by name. It starts on demand.
    const sandbox = getSandbox(env.Sandbox, "agent-session-47");

    // Clone a repository into it.
    await sandbox.gitCheckout("https://github.com/org/repo", {
      targetDir: "/workspace",
      depth: 1,
    });

    // Run the test suite. Stream output back in real time.
    return sandbox.exec("npm", ["test"], { stream: true });
  },
};

As long as you provide the same ID, subsequent requests can get to this same sandbox from anywhere in the world.

Secure credential injection

One of the hardest problems in agentic workloads is authentication. You often need agents to access private services, but you can’t fully trust them with raw credentials. 

Sandboxes solve this by injecting credentials at the network layer using a programmable egress proxy. This means that sandbox agents never have access to credentials and you can fully customize auth logic as you see fit:

class OpenCodeInABox extends Sandbox {
  static outboundByHost = {
    "my-internal-vcs.dev": (request, env, ctx) => {
      const headersWithAuth = new Headers(request.headers);
      headersWithAuth.set("x-auth-token", env.SECRET);
      return fetch(request, { headers: headersWithAuth });
    }
  }
}

For a deep dive into how this works — including identity-aware credential injection, dynamically modifying rules, and integrating with Workers bindings — read our recent blog post on Sandbox auth.

A real terminal, not a simulation

Early agent systems often modeled shell access as a request-response loop: run a command, wait for output, stuff the transcript back into the prompt, repeat. It works, but it is not how developers actually use a terminal. 

Humans run something, watch output stream in, interrupt it, reconnect later, and keep going. Agents benefit from that same feedback loop.

In February, we shipped PTY support. A pseudo-terminal session in a Sandbox, proxied over WebSocket, compatible with xterm.js.

Just call sandbox.terminal to serve the backend:

// Worker: upgrade a WebSocket connection into a live terminal session
export default {
  async fetch(request: Request, env: Env) {
    const url = new URL(request.url);
    if (url.pathname === "/terminal") {
      const sandbox = getSandbox(env.Sandbox, "my-session");
      return sandbox.terminal(request, { cols: 80, rows: 24 });
    }
    return new Response("Not found", { status: 404 });
  },
};

And use xterm addon to call it from the client:

// Browser: connect xterm.js to the sandbox shell
import { Terminal } from "xterm";
import { SandboxAddon } from "@cloudflare/sandbox/xterm";

const term = new Terminal();
const addon = new SandboxAddon({
  getWebSocketUrl: ({ origin }) => `${origin}/terminal`,
});

term.loadAddon(addon);
term.open(document.getElementById("terminal-container")!);
addon.connect({ sandboxId: "my-session" });

This allows agents and developers to use a full PTY to debug those sessions live.


Each terminal session gets its own isolated shell, its own working directory, its own environment. Open as many as you need, just like you would on your own machine. Output is buffered server-side, so reconnecting replays what you missed.

A code interpreter that remembers

For data analysis, scripting, and exploratory workflows, we also ship a higher-level abstraction: a persistent code execution context.

The key word is “persistent.” Many code interpreter implementations run each snippet in isolation, so state disappears between calls. You can’t set a variable in one step and read it in the next.

Sandboxes allow you to create “contexts” that persist state. Variables and imports persist across calls the same way they would in a Jupyter notebook:

// Create a Python context. State persists for its lifetime.
const ctx = await sandbox.createCodeContext({ language: "python" });

// First execution: load data
await sandbox.runCode(`
  import pandas as pd
  df = pd.read_csv('/workspace/sales.csv')
  df['margin'] = (df['revenue'] - df['cost']) / df['revenue']
`, { context: ctx });

// Second execution: df is still there
const result = await sandbox.runCode(`
  df.groupby('region')['margin'].mean().sort_values(ascending=False)
`, { context: ctx, onStdout: (line) => console.log(line.text) });

// result contains matplotlib charts, structured json output, and Pandas tables in HTML

Start a server. Get a URL. Ship it.

Agents are more useful when they can build something and show it to the user immediately. Sandboxes support background processes, readiness checks, and preview URLs. This lets an agent start a development server and share a live link without leaving the conversation.

// Start a dev server as a background process
const server = await sandbox.startProcess("npm run dev", {
  cwd: "/workspace",
});

// Wait until the server is actually ready — don't just sleep and hope
await server.waitForLog(/Local:.*localhost:(\d+)/);

// Expose the running service with a public URL
const { url } = await sandbox.exposePort(3000);

// url is a live public URL the agent can share with the user
console.log(`Preview: ${url}`);

With waitForPort() and waitForLog(), agents can sequence work based on real signals from the running program instead of guesswork. This is much nicer than a common alternative, which is usually some version of sleep(2000) followed by hope.

Watch the file system and reach immediately

Modern development loops are event-driven. Save a file, rerun the build. Edit a config, restart the server. Change a test, rerun the suite.

We shipped sandbox.watch() in March. It returns an SSE stream backed by native inotify, the kernel mechanism Linux uses for filesystem events.

import { parseSSEStream, type FileWatchSSEEvent } from '@cloudflare/sandbox';

const stream = await sandbox.watch('/workspace/src', {
  recursive: true,
  include: ['*.ts', '*.tsx']
});

for await (const event of parseSSEStream<FileWatchSSEEvent>(stream)) {
  if (event.type === 'modify' && event.path.endsWith('.ts')) {
    await sandbox.exec('npx tsc --noEmit', { cwd: '/workspace' });
  }
}

This is one of those primitives that quietly changes what agents can do. An agent that can observe the filesystem in real time can participate in the same feedback loops as a human developer.

Waking up quickly with snapshots

Imagine a (human) developer working on their laptop. They git clone a repo, run npm install, write code, push a PR, then close their laptop while waiting for code review. When it’s time to resume work, they just re-open the laptop and continue where they left off.

If an agent wants to replicate this workflow on a naive container platform, you run into a snag. How do you resume where you left off quickly? You could keep a sandbox running, but then you pay for idle compute. You could start fresh from the container image, but then you have to wait for a long git clone and npm install.

Our answer is snapshots, which will be rolling out in the coming weeks.

A snapshot preserves a container’s full disk state, OS config, installed dependencies, modified files, data files and more. Then it lets you quickly restore it later.

You can configure a Sandbox to automatically snapshot when it goes to sleep.

class AgentDevEnvironment extends Sandbox {
  sleepAfter = "5m";
  persistAcrossSessions = {type: "disk"}; // you can also specify individual directories
}

You can also programmatically take a snapshot and manually restore it. This is useful for checkpointing work or forking sessions. For instance, if you wanted to run four instances of an agent in parallel, you could easily boot four sandboxes from the same state.

class AgentDevEnvironment extends Sandbox {}

async forkDevEnvironment(baseId, numberOfForks) {
  const baseInstance = await getSandbox(baseId);
  const snapshotId = await baseInstance.snapshot();

  const forks = Array.from({ length: numberOfForks }, async (_, i) => {
    const newInstance = await getSandbox(`${baseId}-fork-${i}`);
    return newInstance.start({ snapshot: snapshotId });
  });

  await Promise.all(forks);
}

Snapshots are stored in R2 within your account, giving you durability and location-independence. R2’s tiered caching system allows for fast restores across all of Region: Earth.

In future releases, live memory state will also be captured, allowing running processes to resume exactly where they left off. A terminal and an editor will reopen in the exact state they were in when last closed.

If you are interested in restoring session state before snapshots go live, you can use the backup and restore methods today. These also persist and restore directories using R2, but are not as performant as true VM-level snapshots. Though they still can lead to considerable speed improvements over naively recreating session state.


Booting a sandbox, cloning  ‘axios’, and npm installing takes 30 seconds. Restoring from a backup takes two seconds.

Stay tuned for the official snapshot release.

Higher limits and Active CPU Pricing

Since our initial launch, we’ve been steadily increasing capacity. Users on our standard pricing plan can now run 15,000 concurrent instances of the lite instance type, 6,000 instances of basic, and over 1,000 concurrent larger instances. Reach out to run even more!

We also changed our pricing model to be more cost effective running at scale. Sandboxes now only charge for actively used CPU cycles. This means that you aren’t paying for idle CPU while your agent is waiting for an LLM to respond.

This is what a computer looks like 

Nine months ago, we shipped a sandbox that could run commands and access a filesystem. That was enough to prove the concept.

What we have now is different in kind. A Sandbox today is a full development environment: a terminal you can connect a browser to, a code interpreter with persistent state, background processes with live preview URLs, a filesystem that emits change events in real time, egress proxies for secure credential injection, and a snapshot mechanism that makes warm starts nearly instant. 

When you build on this, a satisfying pattern emerges: agents that do real engineering work. Clone a repo, install it, run the tests, read the failures, edit the code, run the tests again. The kind of tight feedback loop that makes a human engineer effective — now the agent gets it too.

We’re at version 0.8.9 of the SDK. You can get started today:

npm i @cloudflare/sandbox@latest

Dynamic, identity-aware, and secure Sandbox auth

Post Syndicated from Mike Nomitch original https://blog.cloudflare.com/sandbox-auth/

As AI Large Language Models and harnesses like OpenCode and Claude Code become increasingly capable, we see more users kicking off sandboxed agents in response to chat messages, Kanban updates, vibe coding UIs, terminal sessions, GitHub comments, and more.

The sandbox is an important step beyond simple containers, because it gives you a few things:

  • Security: Any untrusted end user (or a rogue LLM) can run in the sandbox and not compromise the host machine or other sandboxes running alongside it. This is traditionally (but not always) accomplished with a microVM.

  • Speed: An end user should be able to pick up a new sandbox quickly and restore the state from a previously used one quickly.

  • Control: The trusted platform needs to be able to take actions within the untrusted domain of the sandbox. This might mean mounting files in the sandbox, or controlling which requests access it, or executing specific commands.

Today, we’re excited to add another key component of control to our Sandboxes and all Containers: outbound Workers. These are programmatic egress proxies that allow users running sandboxes to easily connect to different services, add observability, and, importantly for agents, add flexible and safe authentication.

How it works

Here’s a quick look at adding a secret key to a header using an outbound Worker:

class OpenCodeInABox extends Sandbox {
  static outboundByHost = {
    "github.com": (request, env, ctx) => {
      const headersWithAuth = new Headers(request.headers);
      headersWithAuth.set("x-auth-token", env.SECRET);
      return fetch(request, { headers: headersWithAuth });
    }
  }
}

Any time code running in the sandbox makes a request to “github.com”, the request is proxied through the handler. This allows you to do anything you want on each request, including logging, modifying, or cancelling it. In this case, we’re safely injecting a secret (more on this later). The proxy runs on the same machine as any sandbox, has access to distributed state, and can be easily modified with simple JavaScript.


We’re excited about all the possibilities this adds to Sandboxes, especially around authentication for agents. Before going into details, let’s back up and take a quick tour of traditional forms of auth, and why we think there’s something better.

Common auth for agentic workloads

The core issue with agentic auth is that we can’t fully trust the workload. While our LLMs aren’t nefarious (at least not yet), we still need to be able to apply protections to ensure they don’t use data inappropriately or take actions they shouldn’t.

A few common methods exist to provide auth to agents, and each has downsides:

Standard API tokens are the most basic method of authentication, typically injected into applications via environment variables or in mounted secrets files. This is the arguably simplest method, but least secure. You have to trust that the sandbox won’t somehow be compromised or accidentally exfiltrate the token while making a request. Since you can’t fully trust the agent, you’ll need to set up token expiry and rotation, which can be a hassle.

Workload identity tokens, such as OIDC tokens, can solve some of this pain. Rather than granting the agent a token with general permissions, you can grant it a token that attests its identity. Now, rather than the agent having direct access to some service with a token, it can exchange an identity token for a very short-lived access token. The OIDC token can be invalidated after a specific agent’s workflow completes, and expiry is easier to manage. One of the biggest downsides of workload identity tokens is the potential inflexibility of integrations. Many services don’t have first-class support for OIDC, so in order to get working integrations with upstream services, platforms will need to roll their own token-exchanging services. This makes adoption difficult.

Custom proxies provide maximum flexibility, and can be paired with workload identity tokens. If you can pass some or all of your sandbox egress through a trusted piece of code, you can insert whatever rules you need. Maybe the upstream service your agent is communicating with has a bad RBAC story, and it can’t provide granular permissions. No problem, just write the controls and permissions yourself! This is a great option for agents that you need to lock down with granular controls. However, how do you intercept all of a sandbox’s traffic? How do you set up a proxy that is dynamic and easily programmable? How do you proxy traffic efficiently? These aren’t easy problems to solve.

With those imperfect methods in mind, what does an ideal auth mechanism look like?

Ideally, it is:

  • Zero trust. No token is ever granted to an untrusted user for any amount of time.

  • Simple. Easy to author. Doesn’t involve a complex system of minting, rotating, and decrypting tokens.

  • Flexible. We don’t rely on the upstream system to provide the granular access we need. We can apply whatever rules we want.

  • Identity-aware. We can identify the sandbox making the call and apply specific rules for it.

  • Observable. We can easily gather information about what calls are being made.

  • Performant. We aren’t round-tripping to a centralized or slow source of truth.

  • Transparent. The sandboxed workload doesn’t have to know about it. Things just work.

  • Dynamic. We can change rules on the fly.

We believe outbound Workers for Sandboxes fit the bill on all of these. Let’s see how.

Outbound Workers in practice

Basics: restriction and observability

First, we’ll look at a very basic example: logging requests and denying specific actions.

In this case, we’ll use the outbound function, which intercepts all outgoing HTTP requests from the sandbox. With a few lines of JavaScript, it’s easy to ensure only GETs are made and log then deny any disallowed methods.

class MySandboxedApp extends Sandbox {
  static outbound = (req, env, ctx) => {
    // Deny any non-GET action and log
    if (req.method !== 'GET') {
      console.log(`Container making ${req.method} request to: ${req.url}`);
      return new Response('Not Allowed', { status: 405, statusText: 'Method Not Allowed'});
    }

    // Proceed if it is a GET request
    return fetch(req);
  };
}

This proxy runs on Workers and runs on the same machine as the sandboxed VM. Workers were built for quick response times, often sitting in front of cached CDN traffic, so additional latency is extremely minimal.

Because this is running on Workers, we get observability out of the box. You can view logs and outbound requests in the Workers dashboard or export them to your application performance monitoring tool of choice.

Zero trust credential injection

How would we use this to enforce a zero trust environment for our agent? Let’s imagine we want to make a request to a private GitHub instance, but we never want our LLM to access a private token.

We can use outboundByHost to define functions for specific domains or IPs. In this case, we’ll inject a protected credential if the domain is “my-internal-vcs.dev”. The sandboxed agent never has access to these credentials.

class OpenCodeInABox extends Sandbox {
  static outboundByHost = {
    "my-internal-vcs.dev": (request, env, ctx) => {
      const headersWithAuth = new Headers(request.headers);
      headersWithAuth.set("x-auth-token", env.SECRET);
      return fetch(request, { headers: headersWithAuth });
    }
  }
}

It is also easy to conditionalize the response based on the identity of the container. You don’t have to inject the same tokens for every sandbox instance.

 static outboundByHost = {
  "my-internal-vcs.dev": (request, env, ctx) => {
    // note: KV is encrypted at rest and in transit
    const authKey = await env.KEYS.get(ctx.containerId);

    const requestWithAuth = new Request(request);
    requestWithAuth.headers.set("x-auth-token", authKey);
    return fetch(requestWithAuth);
  }
}

Using the Cloudflare Developer Platform

As you may have noticed in the last example, another major advantage of using outbound Workers is that it makes integration into the Workers ecosystem easier. Previously, if a user wanted to access R2, they would have to inject an R2 credential, then make a call from their container to the public R2 API. Same for KV, Agents, other Containers, other Worker services, etc.

Now, you just call any binding from your outbound Workers.

class MySandboxedApp extends Sandbox {
  static outboundByHost = {
    "my.kv": async (req, env, ctx) => {
      const key = keyFromReq(req);
      const myResult = await env.KV.get(key);
      return new Response(myResult);
    },
    "objects.cf": async (req, env, ctx) => {
      const prefix = ctx.containerId
      const path = pathFromRequest(req);
      const object = await env.R2.get(`${prefix}/${path}`);
      const myResult = await env.KV.get(key);
      return new Response(myResult);
    },
  };
}

Rather than parsing tokens and setting up policies, we can easily conditionalize access with code and whatever logic we want. In the R2 example, we also were able to use the sandbox’s ID to further scope access with ease.

Making controls dynamic

Networking control should also be dynamic. On many platforms, config for Container and VM networking is static, looking something like this:

{
  defaultEgress: "block",
  allowedDomains: ["github.com", "npmjs.org"]
}

This is better than nothing, but we can do better. For many sandboxes, we might want to apply a policy on start, but then override it with another once specific operations have been performed.

For instance, we can boot a sandbox, grab our dependencies via NPM and Github, and then lock down egress after that. This ensures that we open up the network for as little time as possible.

To achieve this, we can use outboundHandlers, which allows us to define arbitrary outbound handlers that can be applied programmatically using the setOutboundHandler method. Each of these also takes params, allowing you to customize behavior from code. In this case, we will allow some hostnames with the custom “allowHosts” policy, then turn off HTTP.

class MySandboxedApp extends Sandbox {
  static outboundHandlers = {
    async allowHosts(req, env, { params }) {
     const url = new URL(request.url);
     const allowedHostname = params.allowedHostnames.includes(url.hostname);

      if (allowedHostname) {
        return await fetch(newRequest);
      } else {
        return new Response(null, { status: 403, statusText: "Forbidden" });
      }
    }
    
    async noHttp(req) {
      return new Response(null, { status: 403, statusText: "Forbidden" });
    }
  }
}

async setUpSandboxes(req, env) {
  const sandbox = await env.SANDBOX.getByName(userId);
  await sandbox.setOutboundHandler("allowHosts", {
    allowedHostnames: ["github.com", "npmjs.org"]
  });
  await sandbox.gitClone(userRepoURL)
  await sandbox.exec("npm install")
  await sandbox.setOutboundHandler("noHttp");
}

This could be extended even further. Your agent might ask the end user a question like “Do you want to allow POST requests to cloudflare.com?” based on whatever tools it needs at that time. With dynamic outbound Workers, you can easily modify the sandbox rules on the fly to provide this level of control.

TLS support with MITM Proxying

To do anything useful with requests beyond allowing or denying them, you need to have access to the content. This means that if you’re making HTTPS requests, they need to be decrypted by the Workers proxy.

To achieve this, a unique ephemeral certificate authority (CA) and private key are created for each Sandbox instance, and the CA is placed into the sandbox. By default, sandbox instances will trust this CA, while standard container instances can opt into trusting it, for instance by calling sudo update-ca-certificates.

export class MyContainer extends Container {
  interceptHttps = true;
}

MyContainer.outbound = (req, env, ctx) => {
  // All HTTP(S) requests will trigger this hook.
  return fetch(req);
};

TLS traffic is proxied by a Cloudflare isolated network process by performing a TLS handshake. It creates a leaf CA from an ephemeral and unique private key and uses the SNI extracted in the ClientHello. It will then invoke in the same machine the  configured Worker to handle the HTTPS request.

Our ephemeral private key and CA will never leave our container runtime sidecar process, and is never shared across other container sidecar processes.

With this in place, outbound Workers act as a truly transparent proxy. The sandbox doesn’t need any awareness of specific protocols or domains — all HTTP and HTTPS traffic flows through the outbound handler for filtering or modification.

Under the hood

To enable the functionality shown above in both Container and Sandbox, we added new methods to the ctx.container object: interceptOutboundHttp and interceptOutboundHttps, which intercept outgoing requests on specific hostnames (with basic glob matching), IP ranges, and it can be used to intercept all outbound requests. These methods are called with a WorkerEntrypoint, which gets set up as the front door to the outbound Worker.

export class MyWorker extends WorkerEntrypoint {
 fetch() {
   return new Response(this.ctx.props.message);
 }
}

// ... inside your container DurableObject ...
this.ctx.container.start({ enableInternet: false });
const outboundWorker = this.ctx.exports.MyWorker({ props: { message: 'hello' } });
await this.ctx.container.interceptOutboundHttp('15.0.0.1:80', outboundWorker);

// From now on, all HTTP requests to 15.0.0.1:80 return "hello"
await this.waitForContainerToBeHealthy();

// You can decide to return another message now...
const secondOutboundWorker = this.ctx.exports.MyWorker({ props: { message: 'switcheroo' } });
await this.ctx.container.interceptOutboundHttp('15.0.0.1:80', secondOutboundWorker);
// all HTTP requests to 15.0.0.1 now show "switcheroo", even on connections that were
// open before this interceptOutboundHttp

// You can even set hostnames, CIDRs, for both IPv4 and IPv6
await this.ctx.container.interceptOutboundHttp('example.com', secondOutboundWorker);
await this.ctx.container.interceptOutboundHttp('*.example.com', secondOutboundWorker);
await this.ctx.container.interceptOutboundHttp('123.123.123.123/23', secoundOutboundWorker);

All proxying to Workers happens locally on the same machine that runs the sandbox VM. Even though communication between container and Worker is “authless”, it is secure.

These methods can be called at any time, before or after starting the container, even while connections are still open. Connections that send multiple HTTP requests will automatically pick up a new entrypoint, so updating outbound Workers will not break existing TCP connections or interrupt HTTP requests.


Local development with wrangler dev also has support for egress interception. To make it possible, we automatically spawn a sidecar process inside the local container’s network namespace. We called this sidecar component proxy-everything. Once proxy-everything is attached, it applies the appropriate TPROXY nftable rules, routing matching traffic from the local Container to workerd, Cloudflare’s open source JavaScript runtime, which runs the outbound Worker. This allows the local development experience to mirror what happens in prod, so testing and development remain simple.

Giving outbound Workers a try

If you haven’t tried Cloudflare Sandboxes, check out the Getting Started guide. If you are a current user of Containers or Sandboxes, start using outbound Workers now by reading the documentation and upgrading to @cloudflare/[email protected] or @cloudflare/[email protected].

Welcome to Agents Week

Post Syndicated from Rita Kozlov original https://blog.cloudflare.com/welcome-to-agents-week/

Cloudflare’s mission has always been to help build a better Internet. Sometimes that means building for the Internet as it exists. Sometimes it means building for the Internet as it’s about to become. 

Today, we’re kicking off Agents Week, dedicated to building the Internet for what comes next.

The Internet wasn’t built for the age of AI. Neither was the cloud.

The cloud, as we know it, was a product of the last major technological paradigm shift: smartphones.

When smartphones put the Internet in everyone’s pocket, they didn’t just add users — they changed the nature of what it meant to be online. Always connected, always expecting an instant response. Applications had to handle an order of magnitude more users, and the infrastructure powering them had to evolve.

The approach the industry converged on was straightforward: more users, more copies of your application. As applications grew in complexity, teams broke them into smaller pieces — microservices — so each team could control its own destiny. But the core principle stayed the same: a finite number of applications, each serving many users. Scale meant more copies.

Kubernetes and containers became the default. They made it easy to spin up instances, load balance, and tear down what you didn’t need. Under this one-to-many model, a single instance could serve many users, and even as user counts grew into the billions, the number of things you had to manage stayed finite.

Agents break this.

One user, one agent, one task

Unlike every application that came before them, agents are one-to-one. Each agent is a unique instance. Serving one user, running one task. Where a traditional application follows the same execution path regardless of who’s using it, an agent requires its own execution environment: one where the LLM dictates the code path, calls tools dynamically, adjusts its approach, and persists until the task is done.

Think of it as the difference between a restaurant and a personal chef. A restaurant has a menu — a fixed set of options — and a kitchen optimized to churn them out at volume. That’s most applications today. An agent is more like a personal chef who asks: what do you want to eat? They might need entirely different ingredients, utensils, or techniques each time. You can’t run a personal-chef service out of the same kitchen setup you’d use for a restaurant.

Over the past year, we’ve seen agents take off, with coding agents leading the way — not surprisingly, since developers tend to be early adopters. The way most coding agents work today is by spinning up a container to give the LLM what it needs: a filesystem, git, bash, and the ability to run arbitrary binaries.

But coding agents are just the beginning. Tools like Claude Cowork are already making agents accessible to less technical users. Once agents move beyond developers and into the hands of everyone — administrative assistants, research analysts, customer service reps, personal planners — the scale math gets sobering fast.

The math on scaling agents to the masses

If the more than 100 million knowledge workers in the US each used an agentic assistant at ~15% concurrency, you’d need capacity for approximately 24 million simultaneous sessions. At 25–50 users per CPU, that’s somewhere between 500K and 1M server CPUs — just for the US, with one agent per person.

Now picture each person running several agents in parallel. Now picture the rest of the world with more than 1 billion knowledge workers. We’re not a little short on compute. We’re orders of magnitude away.

So how do we close that gap?

Infrastructure built for agents

Eight years ago, we launched Workers — the beginning of our developer platform, and a bet on containerless, serverless compute. The motivation at the time was practical: we needed lightweight compute without cold-starts for customers who depended on Cloudflare for speed. Built on V8 isolates rather than containers, Workers turned out to be an order of magnitude more efficient — faster to start, cheaper to run, and natively suited to the “spin up, execute, tear down” pattern.

What we didn’t anticipate was how well this model would map to the age of agents.

Where containers give every agent a full commercial kitchen: bolted-down appliances, walk-in fridges, the works, whether the agent needs them or not, isolates, on the other hand, give the personal chef exactly the counter space, the burner, and the knife they need for this particular meal. Provisioned in milliseconds. Cleaned up the moment the dish is served.


In a world where we need to support not thousands of long-running applications, but billions of ephemeral, single-purpose execution environments — isolates are the right primitive. 

Each one starts in milliseconds. Each one is securely sandboxed. And you can run orders of magnitude more of them on the same hardware compared to containers.

Just a few weeks ago, we took this further with the Dynamic Workers open beta: execution environments spun up at runtime, on demand. An isolate takes a few milliseconds to start and uses a few megabytes of memory. That’s roughly 100x faster and up to 100x more memory-efficient than a container. 

You can start a new one for every single request, run a snippet of code, and throw it away — at a scale of millions per second.

For agents to move beyond early adopters and into everyone’s hands, they also have to be affordable. Running each agent in its own container is expensive enough that agentic tools today are mostly limited to coding assistants for engineers who can justify the cost. Isolates, by running orders of magnitude more efficiently, are what make per-unit economics viable at the scale agents require.


The horseless carriage phase

While it’s critical to build the right foundation for the future, we’re not there yet. And every paradigm shift has a period where we try to make the new thing work within the old model. The first cars were called “horseless carriages.” The first websites were digital brochures. The first mobile apps were shrunken desktop UIs. We’re in that phase now with agents.

You can see it everywhere. 

We’re giving agents headless browsers to navigate websites designed for human eyes, when what they need are structured protocols like MCP to discover and invoke services directly. 

Many early MCP servers are thin wrappers around existing REST APIs — same CRUD operations, new protocol — when LLMs are actually far better at writing code than making sequential tool calls. 

We’re using CAPTCHAs and behavioral fingerprinting to verify the thing on the other end of a request, when increasingly that thing is an agent acting on someone’s behalf — and the right question isn’t “are you human?” but “which agent are you, who authorized you, and what are you allowed to do?”

We’re spinning up full containers for agents that just need to make a few API calls and return a result.

These are just a few examples, but none of this is surprising. It’s what transitions look like.

Building for both

The Internet is always somewhere between two eras. IPv6 is objectively better than IPv4, but dropping IPv4 support would break half the Internet. HTTP/2 and HTTP/3 coexist. TLS 1.2 still hasn’t fully given way to 1.3. The better technology exists, the old technology persists, and the job of infrastructure is to bridge both.

Cloudflare has always been in the business of bridging these transitions. The shift to agents is no different.

Coding agents genuinely need containers — a filesystem, git, bash, arbitrary binary execution. That’s not going away. This week, our container-based sandbox environments are going GA, because we’re committed to making them the best they can be. We’re going deeper on browser rendering for agents, because there will be a long tail of services that don’t yet speak MCP, and agents will still need to interact with them. These aren’t stopgaps — they’re part of a complete platform.

But we’re also building what comes next: the isolates, the protocols, and the identity models that agents actually need. Our job is to make sure you don’t have to choose between what works today and what’s right for tomorrow.

Security in the model, not around it

If agents are going to handle our professional and personal tasks — reading our email, operating on our code, interacting with our financial services — then security has to be built into the execution model, not layered on after the fact.

CISOs have been the first to confront this. The productivity gains from putting agents in everyone’s hands are real, but today, most agent deployments are fraught with risk: prompt injection, data exfiltration, unauthorized API access, opaque tool usage. 

A developer’s vibe-coding agent needs access to repositories and deployment pipelines. An enterprise’s customer service agent needs access to internal APIs and user data. In both cases, securing the environment today means stitching together credentials, network policies, and access controls that were never designed for autonomous software.

Cloudflare has been building two platforms in parallel: our developer platform, for people who build applications, and our zero trust platform, for organizations that need to secure access. For a while, these served distinct audiences. 

But “how do I build this agent?” and “how do I make sure it’s safe?” are increasingly the same question. We’re bringing these platforms together so that all of this is native to how agents run, not a separate layer you bolt on.

Agents that follow the rules

There’s another dimension to the agent era that goes beyond compute and security: economics and governance.

When agents interact with the Internet on our behalf — reading articles, consuming APIs, accessing services — there needs to be a way for the people and organizations who create that content and run those services to set terms and get paid. Today, the web’s economic model is built around human attention: ads, paywalls, subscriptions. 

Agents don’t have attention (well, not that kind of attention). They don’t see ads. They don’t click through cookie banners.

If we want an Internet where agents can operate freely and where publishers, content creators, and service providers are fairly compensated, we need new infrastructure for it. We’re building tools that make it easy for publishers and content owners to set and enforce policies for how agents interact with their content.

Building a better Internet has always meant making sure it works for everyone — not just the people building the technology, but the people whose work and creativity make the Internet worth using. That doesn’t change in the age of agents. It becomes more important.

The platform for developers and agents

Our vision for the developer platform has always been to provide a comprehensive platform that just works: from experiment, to MVP, to scaling to millions of users. But providing the primitives is only part of the equation. A great platform also has to think about how everything works together, and how it integrates into your development flow.

That job is evolving. It used to be purely about developer experience, making it easy for humans to build, test, and ship. Increasingly, it’s also about helping agents help humans, and making the platform work not just for the people building agents, but for the agents themselves. Can an agent find the latest most up-to- date best practices? How easily can it discover and invoke the tools and CLIs it needs? How seamlessly can it move from writing code to deploying it?

This week, we’re shipping improvements across both dimensions — making Cloudflare better for the humans building on it and for the agents running on it.

Building for the future is a team sport

Building for the future is not something we can do alone. Every major Internet transition from HTTP/1.1 to HTTP/2 and HTTP/3, from TLS 1.2 to 1.3 — has required the industry to converge on shared standards. The shift to agents will be no different.

Cloudflare has a long history of contributing to and helping push forward the standards that make the Internet work. We’ve been deeply involved in the IETF for over a decade, helping develop and deploy protocols like QUIC, TLS 1.3, and Encrypted Client Hello. We were a founding member of WinterTC, the ECMA technical committee for JavaScript runtime interoperability. We open-sourced the Workers runtime itself, because we believe the foundation should be open.

We’re bringing the same approach to the agentic era. We’re excited to be part of the Linux Foundation and AAIF, and to help support and push forward standards like MCP that will be foundational for the agentic future. Since Anthropic introduced MCP, we’ve worked closely with them to build the infrastructure for remote MCP servers, open-sourced our own implementations, and invested in making the protocol practical at scale. 

Last year, alongside Coinbase, we co-founded the x402 Foundation, an open, neutral standard that revives the long-dormant HTTP 402 status code to give agents a native way to pay for the services and content they consume. 

Agent identity, authorization, payment, safety: these all need open standards that no single company can define alone.

Stay tuned

This week, we’re making announcements across every dimension of the agent stack: compute, connectivity, security, identity, economics, and developer experience.

The Internet wasn’t built for AI. The cloud wasn’t built for agents. But Cloudflare has always been about helping build a better Internet — and what “better” means changes with each era. This is the era of agents. This week, follow along and we’ll show you what we’re building for it.

Sandboxing AI agents, 100x faster

Post Syndicated from Kenton Varda original https://blog.cloudflare.com/dynamic-workers/

Last September we introduced Code Mode, the idea that agents should perform tasks not by making tool calls, but instead by writing code that calls APIs. We’ve shown that simply converting an MCP server into a TypeScript API can cut token usage by 81%. We demonstrated that Code Mode can also operate behind an MCP server instead of in front of it, creating the new Cloudflare MCP server that exposes the entire Cloudflare API with just two tools and under 1,000 tokens.

But if an agent (or an MCP server) is going to execute code generated on-the-fly by AI to perform tasks, that code needs to run somewhere, and that somewhere needs to be secure. You can’t just eval() AI-generated code directly in your app: a malicious user could trivially prompt the AI to inject vulnerabilities.

You need a sandbox: a place to execute code that is isolated from your application and from the rest of the world, except for the specific capabilities the code is meant to access.

Sandboxing is a hot topic in the AI industry. For this task, most people are reaching for containers. Using a Linux-based container, you can start up any sort of code execution environment you want. Cloudflare even offers our container runtime and our Sandbox SDK for this purpose.

But containers are expensive and slow to start, taking hundreds of milliseconds to boot and hundreds of megabytes of memory to run. You probably need to keep them warm to avoid delays, and you may be tempted to reuse existing containers for multiple tasks, compromising the security.

If we want to support consumer-scale agents, where every end user has an agent (or many!) and every agent writes code, containers are not enough. We need something lighter.

And we have it.

Dynamic Worker Loader: a lean sandbox

Tucked into our Code Mode post in September was the announcement of a new, experimental feature: the Dynamic Worker Loader API. This API allows a Cloudflare Worker to instantiate a new Worker, in its own sandbox, with code specified at runtime, all on the fly.

Dynamic Worker Loader is now in open beta, available to all paid Workers users.

Read the docs for full details, but here’s what it looks like:

// Have your LLM generate code like this.
let agentCode: string = `
  export default {
    async myAgent(param, env, ctx) {
      // ...
    }
  }
`;

// Get RPC stubs representing APIs the agent should be able
// to access. (This can be any Workers RPC API you define.)
let chatRoomRpcStub = ...;

// Load a worker to run the code, using the worker loader
// binding.
let worker = env.LOADER.load({
  // Specify the code.
  compatibilityDate: "2026-03-01",
  mainModule: "agent.js",
  modules: { "agent.js": agentCode },

  // Give agent access to the chat room API.
  env: { CHAT_ROOM: chatRoomRpcStub },

  // Block internet access. (You can also intercept it.)
  globalOutbound: null,
});

// Call RPC methods exported by the agent code.
await worker.getEntrypoint().myAgent(param);

That’s it.

100x faster

Dynamic Workers use the same underlying sandboxing mechanism that the entire Cloudflare Workers platform has been built on since its launch, eight years ago: isolates. An isolate is an instance of the V8 JavaScript execution engine, the same engine used by Google Chrome. They are how Workers work.

An isolate takes a few milliseconds to start and uses a few megabytes of memory. That’s around 100x faster and 10x-100x more memory efficient than a typical container.

That means that if you want to start a new isolate for every user request, on-demand, to run one snippet of code, then throw it away, you can.

Unlimited scalability

Many container-based sandbox providers impose limits on global concurrent sandboxes and rate of sandbox creation. Dynamic Worker Loader has no such limits. It doesn’t need to, because it is simply an API to the same technology that has powered our platform all along, which has always allowed Workers to seamlessly scale to millions of requests per second.

Want to handle a million requests per second, where every single request loads a separate Dynamic Worker sandbox, all running concurrently? No problem!

Zero latency

One-off Dynamic Workers usually run on the same machine — the same thread, even — as the Worker that created them. No need to communicate around the world to find a warm sandbox. Isolates are so lightweight that we can just run them wherever the request landed. Dynamic Workers are supported in every one of Cloudflare’s hundreds of locations around the world.

It’s all JavaScript

The only catch, vs. containers, is that your agent needs to write JavaScript.

Technically, Workers (including dynamic ones) can use Python and WebAssembly, but for small snippets of code — like that written on-demand by an agent — JavaScript will load and run much faster.

We humans tend to have strong preferences on programming languages, and while many love JavaScript, others might prefer Python, Rust, or countless others.

But we aren’t talking about humans here. We’re talking about AI. AI will write any language you want it to. LLMs are experts in every major language. Their training data in JavaScript is immense.

JavaScript, by its nature on the web, is designed to be sandboxed. It is the correct language for the job.

Tools defined in TypeScript

If we want our agent to be able to do anything useful, it needs to talk to external APIs. How do we tell it about the APIs it has access to?

MCP defines schemas for flat tool calls, but not programming APIs. OpenAPI offers a way to express REST APIs, but it is verbose, both in the schema itself and the code you’d have to write to call it.

For APIs exposed to JavaScript, there is a single, obvious answer: TypeScript.

Agents know TypeScript. TypeScript is designed to be concise. With very few tokens, you can give your agent a precise understanding of your API.

// Interface to interact with a chat room.
interface ChatRoom {
  // Get the last `limit` messages of the chat log.
  getHistory(limit: number): Promise<Message[]>;

  // Subscribe to new messages. Dispose the returned object
  // to unsubscribe.
  subscribe(callback: (msg: Message) => void): Promise<Disposable>;

  // Post a message to chat.
  post(text: string): Promise<void>;
}

type Message = {
  author: string;
  time: Date;
  text: string;
}

Compare this with the equivalent OpenAPI spec (which is so long you have to scroll to see it all):

openapi: 3.1.0
info:
  title: ChatRoom API
  description: >
    Interface to interact with a chat room.
  version: 1.0.0

paths:
  /messages:
    get:
      operationId: getHistory
      summary: Get recent chat history
      description: Returns the last `limit` messages from the chat log, newest first.
      parameters:
        - name: limit
          in: query
          required: true
          schema:
            type: integer
            minimum: 1
      responses:
        "200":
          description: A list of messages.
          content:
            application/json:
              schema:
                type: array
                items:
                  $ref: "#/components/schemas/Message"

    post:
      operationId: postMessage
      summary: Post a message to the chat room
      requestBody:
        required: true
        content:
          application/json:
            schema:
              type: object
              required:
                - text
              properties:
                text:
                  type: string
      responses:
        "204":
          description: Message posted successfully.

  /messages/stream:
    get:
      operationId: subscribeMessages
      summary: Subscribe to new messages via SSE
      description: >
        Opens a Server-Sent Events stream. Each event carries a JSON-encoded
        Message object. The client unsubscribes by closing the connection.
      responses:
        "200":
          description: An SSE stream of new messages.
          content:
            text/event-stream:
              schema:
                description: >
                  Each SSE `data` field contains a JSON-encoded Message object.
                $ref: "#/components/schemas/Message"

components:
  schemas:
    Message:
      type: object
      required:
        - author
        - time
        - text
      properties:
        author:
          type: string
        time:
          type: string
          format: date-time
        text:
          type: string

We think the TypeScript API is better. It’s fewer tokens and much easier to understand (for both agents and humans).

Dynamic Worker Loader makes it easy to implement a TypeScript API like this in your own Worker and then pass it in to the Dynamic Worker either as a method parameter or in the env object. The Workers Runtime will automatically set up a Cap’n Web RPC bridge between the sandbox and your harness code, so that the agent can invoke your API across the security boundary without ever realizing that it isn’t using a local library.

That means your agent can write code like this:

// Thinking: The user asked me to summarize recent chat messages from Alice.
// I will filter the recent message history in code so that I only have to
// read the relevant messages.
let history = await env.CHAT_ROOM.getHistory(1000);
return history.filter(msg => msg.author == "alice");

HTTP filtering and credential injection

If you prefer to give your agents HTTP APIs, that’s fully supported. Using the globalOutbound option to the worker loader API, you can register a callback to be invoked on every HTTP request, in which you can inspect the request, rewrite it, inject auth keys, respond to it directly, block it, or anything else you might like.

For example, you can use this to implement credential injection (token injection): When the agent makes an HTTP request to a service that requires authorization, you add credentials to the request on the way out. This way, the agent itself never knows the secret credentials, and therefore cannot leak them.

Using a plain HTTP interface may be desirable when an agent is talking to a well-known API that is in its training set, or when you want your agent to use a library that is built on a REST API (the library can run inside the agent’s sandbox).

With that said, in the absence of a compatibility requirement, TypeScript RPC interfaces are better than HTTP:

  • As shown above, a TypeScript interface requires far fewer tokens to describe than an HTTP interface.

  • The agent can write code to call TypeScript interfaces using far fewer tokens than equivalent HTTP.

  • With TypeScript interfaces, since you are defining your own wrapper interface anyway, it is easier to narrow the interface to expose exactly the capabilities that you want to provide to your agent, both for simplicity and security. With HTTP, you are more likely implementing filtering of requests made against some existing API. This is hard, because your proxy must fully interpret the meaning of every API call in order to properly decide whether to allow it, and HTTP requests are complicated, with many headers and other parameters that could all be meaningful. It ends up being easier to just write a TypeScript wrapper that only implements the functions you want to allow.

Battle-hardened security

Hardening an isolate-based sandbox is tricky, as it is a more complicated attack surface than hardware virtual machines. Although all sandboxing mechanisms have bugs, security bugs in V8 are more common than security bugs in typical hypervisors. When using isolates to sandbox possibly-malicious code, it’s important to have additional layers of defense-in-depth. Google Chrome, for example, implemented strict process isolation for this reason, but it is not the only possible solution.

We have nearly a decade of experience securing our isolate-based platform. Our systems automatically deploy V8 security patches to production within hours — faster than Chrome itself. Our security architecture features a custom second-layer sandbox with dynamic cordoning of tenants based on risk assessments. We’ve extended the V8 sandbox itself to leverage hardware features like MPK. We’ve teamed up with (and hired) leading researchers to develop novel defenses against Spectre. We also have systems that scan code for malicious patterns and automatically block them or apply additional layers of sandboxing. And much more.

When you use Dynamic Workers on Cloudflare, you get all of this automatically.

Helper libraries

We’ve built a number of libraries that you might find useful when working with Dynamic Workers:

Code Mode

@cloudflare/codemode simplifies running model-generated code against AI tools using Dynamic Workers. At its core is DynamicWorkerExecutor(), which constructs a purpose-built sandbox with code normalisation to handle common formatting errors, and direct access to a globalOutbound fetcher for controlling fetch() behaviour inside the sandbox — set it to null for full isolation, or pass a Fetcher binding to route, intercept or enrich outbound requests from the sandbox.

const executor = new DynamicWorkerExecutor({
  loader: env.LOADER,
  globalOutbound: null, // fully isolated 
});

const codemode = createCodeTool({
  tools: myTools,
  executor,
});

return generateText({
  model,
  messages,
  tools: { codemode },
});

The Code Mode SDK also provides two server-side utility functions. codeMcpServer({ server, executor }) wraps an existing MCP Server, replacing its tool surface with a single code() tool. openApiMcpServer({ spec, executor, request }) goes further: given an OpenAPI spec and an executor, it builds a complete MCP Server with search() and execute() tools as used by the Cloudflare MCP Server, and better suited to larger APIs.

In both cases, the code generated by the model runs inside Dynamic Workers, with calls to external services made over RPC bindings passed to the executor.

Learn more about the library and how to use it.

Bundling

Dynamic Workers expect pre-bundled modules. @cloudflare/worker-bundler handles that for you: give it source files and a package.json, and it resolves npm dependencies from the registry, bundles everything with esbuild, and returns the module map the Worker Loader expects.

import { createWorker } from "@cloudflare/worker-bundler";

const worker = env.LOADER.get("my-worker", async () => {
  const { mainModule, modules } = await createWorker({
    files: {
      "src/index.ts": `
        import { Hono } from 'hono';
        import { cors } from 'hono/cors';

        const app = new Hono();
        app.use('*', cors());
        app.get('/', (c) => c.text('Hello from Hono!'));
        app.get('/json', (c) => c.json({ message: 'It works!' }));

        export default app;
      `,
      "package.json": JSON.stringify({
        dependencies: { hono: "^4.0.0" }
      })
    }
  });

  return { mainModule, modules, compatibilityDate: "2026-01-01" };
});

await worker.getEntrypoint().fetch(request);

It also supports full-stack apps via createApp — bundle a server Worker, client-side JavaScript, and static assets together, with built-in asset serving that handles content types, ETags, and SPA routing.

Learn more about the library and how to use it.

File manipulation

@cloudflare/shell gives your agent a virtual filesystem inside a Dynamic Worker. Agent code calls typed methods on a state object — read, write, search, replace, diff, glob, JSON query/update, archive — with structured inputs and outputs instead of string parsing.

Storage is backed by a durable Workspace (SQLite + R2), so files persist across executions. Coarse operations like searchFiles, replaceInFiles, and planEdits minimize RPC round-trips — the agent issues one call instead of looping over individual files. Batch writes are transactional by default: if any write fails, earlier writes roll back automatically.

import { Workspace } from "@cloudflare/shell";
import { stateTools } from "@cloudflare/shell/workers";
import { DynamicWorkerExecutor, resolveProvider } from "@cloudflare/codemode";

const workspace = new Workspace({
  sql: this.ctx.storage.sql, // Works with any DO's SqlStorage, D1, or custom SQL backend
  r2: this.env.MY_BUCKET, // large files spill to R2 automatically
  name: () => this.name   // lazy — resolved when needed, not at construction
});

// Code runs in an isolated Worker sandbox with no network access
const executor = new DynamicWorkerExecutor({ loader: env.LOADER });

// The LLM writes this code; `state.*` calls dispatch back to the host via RPC
const result = await executor.execute(
  `async () => {
    // Search across all TypeScript files for a pattern
    const hits = await state.searchFiles("src/**/*.ts", "answer");
    // Plan multiple edits as a single transaction
    const plan = await state.planEdits([
      { kind: "replace", path: "/src/app.ts",
        search: "42", replacement: "43" },
      { kind: "writeJson", path: "/src/config.json",
        value: { version: 2 } }
    ]);
    // Apply atomically — rolls back on failure
    return await state.applyEditPlan(plan);
  }`,
  [resolveProvider(stateTools(workspace))]
);

The package also ships prebuilt TypeScript type declarations and a system prompt template, so you can drop the full state API into your LLM context in a handful of tokens.

Learn more about the library and how to use it.

How are people using it?

Code Mode

Developers want their agents to write and execute code against tool APIs, rather than making sequential tool calls one at a time. With Dynamic Workers, the LLM generates a single TypeScript function that chains multiple API calls together, runs it in a Dynamic Worker, and returns the final result back to the agent. As a result, only the output, and not every intermediate step, ends up in the context window. This cuts both latency and token usage, and produces better results, especially when the tool surface is large.

Our own Cloudflare MCP server is built exactly this way: it exposes the entire Cloudflare API through just two tools — search and execute — in under 1,000 tokens, because the agent writes code against a typed API instead of navigating hundreds of individual tool definitions.

Building custom automations 

Developers are using Dynamic Workers to let agents build custom automations on the fly. Zite, for example, is building an app platform where users interact through a chat interface — the LLM writes TypeScript behind the scenes to build CRUD apps, connect to services like Stripe, Airtable, and Google Calendar, and run backend logic, all without the user ever seeing a line of code. Every automation runs in its own Dynamic Worker, with access to only the specific services and libraries that the endpoint needs.

“To enable server-side code for Zite’s LLM-generated apps, we needed an execution layer that was instant, isolated, and secure. Cloudflare’s Dynamic Workers hit the mark on all three, and out-performed all of the other platforms we benchmarked for speed and library support. The NodeJS compatible runtime supported all of Zite’s workflows, allowing hundreds of third party integrations, without sacrificing on startup time. Zite now services millions of execution requests daily thanks to Dynamic Workers.”

Antony Toron, CTO and Co-Founder, Zite 

Running AI-generated applications

Developers are building platforms that generate full applications from AI — either for their customers or for internal teams building prototypes. With Dynamic Workers, each app can be spun up on demand, then put back into cold storage until it’s invoked again. Fast startup times make it easy to preview changes during active development. Platforms can also block or intercept any network requests the generated code makes, keeping AI-generated apps safe to run.

Pricing

Dynamically-loaded Workers are priced at $0.002 per unique Worker loaded per day (as of this post’s publication), in addition to the usual CPU time and invocation pricing of regular Workers.

For AI-generated “code mode” use cases, where every Worker is a unique one-off, this means the price is $0.002 per Worker loaded (plus CPU and invocations). This cost is typically negligible compared to the inference costs to generate the code.

During the beta period, the $0.002 charge is waived. As pricing is subject to change, please always check our Dynamic Workers pricing for the most current information. 

Get Started

If you’re on the Workers Paid plan, you can start using Dynamic Workers today. 

Dynamic Workers Starter

Use this “hello world” starter to get a Worker deployed that can load and execute Dynamic Workers. 

Dynamic Workers Playground

You can also deploy the Dynamic Workers Playground, where you’ll be able to write or import code, bundle it at runtime with @cloudflare/worker-bundler, execute it through a Dynamic Worker, see real-time responses and execution logs.


Dynamic Workers are fast, scalable, and lightweight. Find us on Discord if you have any questions. We’d love to see what you build!


Powering the agents: Workers AI now runs large models, starting with Kimi K2.5

Post Syndicated from Michelle Chen original https://blog.cloudflare.com/workers-ai-large-models/

We’re making Cloudflare the best place for building and deploying agents. But reliable agents aren’t built on prompts alone; they require a robust, coordinated infrastructure of underlying primitives.

At Cloudflare, we have been building these primitives for years: Durable Objects for state persistence, Workflows for long running tasks, and Dynamic Workers or Sandbox containers for secure execution. Powerful abstractions like the Agents SDK are designed to help you build agents on top of Cloudflare’s Developer Platform.

But these primitives only provided the execution environment. The agent still needed a model capable of powering it. 

Starting today, Workers AI is officially in the big models game. We now offer frontier open-source models on our AI inference platform. We’re starting by releasing Moonshot AI’s Kimi K2.5 model on Workers AI. With a full 256k context window and support for multi-turn tool calling, vision inputs, and structured outputs, the Kimi K2.5 model is excellent for all kinds of agentic tasks. By bringing a frontier-scale model directly into the Cloudflare Developer Platform, we’re making it possible to run the entire agent lifecycle on a single, unified platform.

The heart of an agent is the AI model that powers it, and that model needs to be smart, with high reasoning capabilities and a large context window. Workers AI now runs those models.

The price-performance sweet spot

We spent the last few weeks testing Kimi K2.5 as the engine for our internal development tools. Within our OpenCode environment, Cloudflare engineers use Kimi as a daily driver for agentic coding tasks. We have also integrated the model into our automated code review pipeline; you can see this in action via our public code review agent, Bonk, on Cloudflare GitHub repos. In production, the model has proven to be a fast, efficient alternative to larger proprietary models without sacrificing quality.

Serving Kimi K2.5 began as an experiment, but it quickly became critical after reviewing how the model performs and how cost-efficient it is. As an illustrative example: we have an agent that does security reviews of Cloudflare’s codebases. This agent processes over 7B tokens per day, and using Kimi, it has caught more than 15 confirmed issues in a single codebase. Doing some rough math, if we had run this agent on a mid-tier proprietary model, we would have spent $2.4M a year for this single use case, on a single codebase. Running this agent with Kimi K2.5 cost just a fraction of that: we cut costs by 77% simply by making the switch to Workers AI.

As AI adoption increases, we are seeing a fundamental shift not only in how engineering teams are operating, but how individuals are operating. It is becoming increasingly common for people to have a personal agent like OpenClaw running 24/7. The volume of inference is skyrocketing.

This new rise in personal and coding agents means that cost is no longer a secondary concern; it is the primary blocker to scaling. When every employee has multiple agents processing hundreds of thousands of tokens per hour, the math for proprietary models stops working. Enterprises will look to transition to open-source models that offer frontier-level reasoning without the proprietary price tag. Workers AI is here to facilitate this shift, providing everything from serverless endpoints for a personal agent to dedicated instances powering autonomous agents across an entire organization.

The large model inference stack

Workers AI has served models, including LLMs, since its launch two years ago, but we’ve historically prioritized smaller models. Part of the reason was that for some time, open-source LLMs fell far behind the models from frontier model labs. This changed with models like Kimi K2.5, but to serve this type of very large LLM, we had to make changes to our inference stack. We wanted to share with you some of what goes on behind the scenes to support a model like Kimi.

We’ve been working on custom kernels for Kimi K2.5 to optimize how we serve the model, which is built on top of our proprietary Infire inference engine. Custom kernels improve the model’s performance and GPU utilization, unlocking gains that would otherwise go unclaimed if you were just running the model out of the box. There are also multiple techniques and hardware configurations that can be leveraged to serve a large model. Developers typically use a combination of data, tensor, and expert parallelization techniques to optimize model performance. Strategies like disaggregated prefill are also important, in which you separate the prefill and generation stages onto different machines in order to get better throughput or higher GPU utilization. Implementing these techniques and incorporating them into the inference stack takes a lot of dedicated experience to get right. 

Workers AI has already done the experimentation with serving techniques to yield excellent throughput on Kimi K2.5. A lot of this does not come out of the box when you self-host an open-source model. The benefit of using a platform like Workers AI is that you don’t need to be a Machine Learning Engineer, a DevOps expert, or a Site Reliability Engineer to do the optimizations required to host it: we’ve already done the hard part, you just need to call an API.

Beyond the model — platform improvements for agentic workloads

In concert with this launch, we’ve also improved our platform and are releasing several new features to help you build better agents.

Prefix caching and surfacing cached tokens

When you work with agents, you are likely sending a large number of input tokens as part of the context: this could be detailed system prompts, tool definitions, MCP server tools, or entire codebases. Inputs can be as large as the model context window, so in theory, you could be sending requests with almost 256k input tokens. That’s a lot of tokens.

When an LLM processes a request, the request is broken down into two stages: the prefill stage processes input tokens and the output stage generates output tokens. These stages are usually sequential, where input tokens have to be fully processed before you can generate output tokens. This means that sometimes the GPU is not fully utilized while the model is doing prefill.

With multi-turn conversations, when you send a new prompt, the client sends all the previous prompts, tools, and context from the session to the model as well. The delta between consecutive requests is usually just a few new lines of input; all the other context has already gone through the prefill stage during a previous request. This is where prefix caching helps. Instead of doing prefill on the entire request, we can cache the input tensors from a previous request, and only do prefill on the new input tokens. This saves a lot of time and compute from the prefill stage, which means a faster Time to First Token (TTFT) and a higher Tokens Per Second (TPS) throughput as you’re not blocked on prefill.

Workers AI has always done prefix caching, but we are now surfacing cached tokens as a usage metric and offering a discount on cached tokens compared to input tokens. (Pricing can be found on the model page.) We also have new techniques for you to leverage in order to get a higher prefix cache hit rate, reducing your costs.

New session affinity header for higher cache hit rates

In order to route to the same model instance and take advantage of prefix caching, we use a new x-session-affinity header. When you send this header, you’ll improve your cache hit ratio, leading to more cached tokens and subsequently, faster TTFT, TPS, and lower inference costs.

You can pass the new header like below, with a unique string per session or per agent. Some clients like OpenCode implement this automatically out of the box. Our Agents SDK starter has already set up the wiring to do this for you, too.

curl -X POST \
"https://api.cloudflare.com/client/v4/accounts/{ACCOUNT_ID}/ai/run/@cf/moonshotai/kimi-k2.5" \
  -H "Authorization: Bearer {API_TOKEN}" \
  -H "Content-Type: application/json" \
  -H "x-session-affinity: ses_12345678" \
  -d '{
    "messages": [
      {
        "role": "system",
        "content": "You are a helpful assistant."
      },
      {
        "role": "user",
        "content": "What is prefix caching and why does it matter?"
      }
    ],
    "max_tokens": 2400,
    "stream": true
  }'

Redesigned async APIs

Serverless inference is really hard. With a pay-per-token business model, it’s cheaper on a single request basis because you don’t need to pay for entire GPUs to service your requests. But there’s a trade-off: you have to contend with other people’s traffic and capacity constraints, and there’s no strict guarantee that your request will be processed. This is not unique to Workers AI — it’s evidently the case across serverless model providers, given the frequent news reports of overloaded providers and service disruptions. While we always strive to serve your request and have built-in autoscaling and rebalancing, there are hard limitations (like hardware) that make this a challenge.

For volumes of requests that would exceed synchronous rate limits, you can submit batches of inferences to be completed asynchronously. We’re introducing a revamped Asynchronous API, which means that for asynchronous use cases, you won’t run into Out of Capacity errors and inference will execute durably at some point. Our async API looks more like flex processing than a batch API, where we process requests in the async queue as long as we have headroom in our model instances. With internal testing, our async requests usually execute within 5 minutes, but this will depend on what live traffic looks like. As we bring Kimi to the public, we will tune our scaling accordingly, but the async API is the best way to make sure you don’t run into capacity errors in durable workflows. This is perfect for use cases that are not real-time, such as code scanning agents or research agents.

Workers AI previously had an asynchronous API, but we’ve recently revamped the systems under the hood. We now rely on a pull-based system versus the historical push-based system, allowing us to pull in queued requests as soon as we have capacity. We’ve also added better controls to tune the throughput of async requests, monitoring GPU utilization in real-time and pulling in async requests when utilization is low, so that critical synchronous requests get priority while still processing asynchronous requests efficiently.

To use the asynchronous API, you would send your requests as seen below. We also have a way to set up event notifications so that you can know when the inference is complete instead of polling for the request. 

// (1.) Push a request in queue
// pass queueRequest: true
let res = await env.AI.run("@cf/moonshotai/kimi-k2.5", {
  "requests": [{
    "messages": [{
      "role": "user",
      "content": "Tell me a joke"
    }]
  }, {
    "messages": [{
      "role": "user",
      "content": "Explain the Pythagoras theorem"
    }]
  }, ...{<add more requests in a batch>} ];
}, {
  queueRequest: true,
});


// (2.) grab the request id
let request_id;
if(res && res.request_id){
  request_id = res.request_id;
}
// (3.) poll the status
let res = await env.AI.run("@cf/moonshotai/kimi-k2.5", {
  request_id: request_id
});

if(res && res.status === "queued" || res.status === "running") {
 // retry by polling again
 ...
}
else 
 return Response.json(res); // This will contain the final completed response 

Try it out today

Get started with Kimi K2.5 on Workers AI today. You can read our developer docs to find out model information and pricing, and how to take advantage of prompt caching via session affinity headers and asynchronous API. The Agents SDK starter also now uses Kimi K2.5 as its default model. You can also connect to Kimi K2.5 on Workers AI via Opencode. For a live demo, try it in our playground.

And if this set of problems around serverless inference, ML optimizations, and GPU infrastructure sound  interesting to you — we’re hiring!


Introducing Markdown for Agents

Post Syndicated from Celso Martinho original https://blog.cloudflare.com/markdown-for-agents/

The way content and businesses are discovered online is changing rapidly. In the past, traffic originated from traditional search engines, and SEO determined who got found first. Now the traffic is increasingly coming from AI crawlers and agents that demand structured data within the often-unstructured Web that was built for humans.

As a business, to continue to stay ahead, now is the time to consider not just human visitors, or traditional wisdom for SEO-optimization, but start to treat agents as first-class citizens. 

Why markdown is important

Feeding raw HTML to an AI is like paying by the word to read packaging instead of the letter inside. A simple ## About Us on a page in markdown costs roughly 3 tokens; its HTML equivalent – <h2 class="section-title" id="about">About Us</h2> – burns 12-15, and that’s before you account for the <div> wrappers, nav bars, and script tags that pad every real web page and have zero semantic value.

This blog post you’re reading takes 16,180 tokens in HTML and 3,150 tokens when converted to markdown. That’s a 80% reduction in token usage.

Markdown has quickly become the lingua franca for agents and AI systems as a whole. The format’s explicit structure makes it ideal for AI processing, ultimately resulting in better results while minimizing token waste.

The problem is that the Web is made of HTML, not markdown, and page weight has been steadily increasing over the years, making pages hard to parse. For agents, their goal is to filter out all non-essential elements and scan the relevant content.

The conversion of HTML to markdown is now a common step for any AI pipeline. Still, this process is far from ideal: it wastes computation, adds costs and processing complexity, and above all, it may not be how the content creator intended their content to be used in the first place.

What if AI agents could bypass the complexities of intent analysis and document conversion, and instead receive structured markdown directly from the source?

Convert HTML to markdown, automatically

Cloudflare’s network now supports real-time content conversion at the source, for enabled zones using content negotiation headers. Now when AI systems request pages from any website that uses Cloudflare and has Markdown for Agents enabled, they can express the preference for text/markdown in the request. Our network will automatically and efficiently convert the HTML to markdown, when possible, on the fly.

Here’s how it works. To fetch the markdown version of any page from a zone with Markdown for Agents enabled, the client needs to add the Accept negotiation header with text/markdown as one of the options. Cloudflare will detect this, fetch the original HTML version from the origin, and convert it to markdown before serving it to the client.

Here’s a curl example with the Accept negotiation header requesting a page from our developer documentation:

curl https://developers.cloudflare.com/fundamentals/reference/markdown-for-agents/ \
  -H "Accept: text/markdown"

Or if you’re building an AI Agent using Workers, you can use TypeScript:

const r = await fetch(
  `https://developers.cloudflare.com/fundamentals/reference/markdown-for-agents/`,
  {
    headers: {
      Accept: "text/markdown, text/html",
    },
  },
);
const tokenCount = r.headers.get("x-markdown-tokens");
const markdown = await r.text();

We already see some of the most popular coding agents today – like Claude Code and OpenCode – send these accept headers with their requests for content. Now, the response to this request is formatted  in markdown. It’s that simple.  

HTTP/2 200
date: Wed, 11 Feb 2026 11:44:48 GMT
content-type: text/markdown; charset=utf-8
content-length: 2899
vary: accept
x-markdown-tokens: 725
content-signal: ai-train=yes, search=yes, ai-input=yes

---
title: Markdown for Agents · Cloudflare Agents docs
---

## What is Markdown for Agents

The ability to parse and convert HTML to Markdown has become foundational for AI.
...

Note that we include an x-markdown-tokens header with the converted response that indicates the estimated number of tokens in the markdown document. You can use this value in your flow, for example to calculate the size of a context window or to decide on your chunking strategy.

Here’s a diagram of how it works:


Content Signals Policy

During our last Birthday Week, Cloudflare announced Content Signals — a framework that allows anyone to express their preferences for how their content can be used after it has been accessed. 

When you return markdown, you want to make sure your content is being used by the Agent or AI crawler. That’s why Markdown for Agents converted responses include the Content-Signal: ai-train=yes, search=yes, ai-input=yes header signaling that indicates content can be used for AI Training, Search results and AI Input, which includes agentic use. Markdown for Agents will provide options to define custom Content Signal policies in the future.

Check our dedicated Content Signals page for more information on this framework.

Try it with the Cloudflare Blog & Developer Documentation 

We enabled this feature in our Developer Documentation and our Blog, inviting all AI crawlers and agents to consume our content using markdown instead of HTML.

Try it out now by requesting this blog with Accept: text/markdown.

curl https://blog.cloudflare.com/markdown-for-agents/ \
  -H "Accept: text/markdown"

The result is:

---
description: The way content is discovered online is shifting, from traditional search engines to AI agents that need structured data from a Web built for humans. It’s time to consider not just human visitors, but start to treat agents as first-class citizens. Markdown for Agents automatically converts any HTML page requested from our network to markdown.
title: Introducing Markdown for Agents
image: https://blog.cloudflare.com/images/markdown-for-agents.png
---

# Introducing Markdown for Agents

The way content and businesses are discovered online is changing rapidly. In the past, traffic originated from traditional search engines and SEO determined who got found first. Now the traffic is increasingly coming from AI crawlers and agents that demand structured data within the often-unstructured Web that was built for humans.

...

Other ways to convert to Markdown

If you’re building AI systems that require arbitrary document conversion from outside Cloudflare or Markdown for Agents is not available from the content source, we provide other ways to convert documents to Markdown for your applications:

  • Workers AI AI.toMarkdown() supports multiple document types, not just HTML, and summarization.

  • Browser Rendering /markdown REST API supports markdown conversion if you need to render a dynamic page or application in a real browser before converting it.

Tracking markdown usage

Anticipating a shift in how AI systems browse the Web, Cloudflare Radar now includes content type insights for AI bot and crawler traffic, both globally on the AI Insights page and in the individual bot information pages.

The new content_type dimension and filter shows the distribution of content types returned to AI agents and crawlers, grouped by MIME type category. 


You can also see the requests for markdown filtered by a specific agent or crawler. Here are the requests that return markdown to OAI-Searchbot, the crawler used by OpenAI to power ChatGPT’s search: 


This new data will allow us to track the evolution of how AI bots, crawlers, and agents are consuming Web content over time. As always, everything on Radar is freely accessible via the public APIs and the Data Explorer

Start using today

To enable Markdown for Agents for your zone, log into the Cloudflare dashboard, select your account, select the zone, look for Quick Actions and toggle the Markdown for Agents button to enable. This feature is available today in Beta at no cost for Pro, Business and Enterprise plans, as well as SSL for SaaS customers.


You can find more information about Markdown for Agents on our Developer Docs. We welcome your feedback as we continue to refine and enhance this feature. We’re curious to see how AI crawlers and agents navigate and adapt to the unstructured nature of the Web as it evolves.

Introducing Moltworker: a self-hosted personal AI agent, minus the minis

Post Syndicated from Celso Martinho original https://blog.cloudflare.com/moltworker-self-hosted-ai-agent/

The Internet woke up this week to a flood of people buying Mac minis to run Moltbot (formerly Clawdbot), an open-source, self-hosted AI agent designed to act as a personal assistant. Moltbot runs in the background on a user’s own hardware, has a sizable and growing list of integrations for chat applications, AI models, and other popular tools, and can be controlled remotely. Moltbot can help you with your finances, social media, organize your day — all through your favorite messaging app.

But what if you don’t want to buy new dedicated hardware? And what if you could still run your Moltbot efficiently and securely online? Meet Moltworker, a middleware Worker and adapted scripts that allows running Moltbot on Cloudflare’s Sandbox SDK and our Developer Platform APIs.

A personal assistant on Cloudflare — how does that work? 

Firstly, Cloudflare Workers has never been so compatible with Node.js. Where in the past we had to mock APIs to get some packages running, now those APIs are supported natively by the Workers Runtime.

This has changed how we can build tools on Cloudflare Workers. When we first implemented Playwright, a popular framework for web testing and automation that runs on Browser Rendering, we had to rely on memfs. This was bad because not only is memfs a hack and an external dependency, but it also forced us to drift away from the official Playwright codebase. Thankfully, with more Node.js compatibility, we were able to start using node:fs natively, reducing complexity and maintainability, which makes upgrades to the latest versions of Playwright easy to do.

The list of Node.js APIs we support natively keeps growing. The blog post “A year of improving Node.js compatibility in Cloudflare Workers” provides an overview of where we are and what we’re doing.

We measure this progress, too. We recently ran an experiment where we took the 1,000 most popular NPM packages, installed and let AI loose, to try to run them in Cloudflare Workers, Ralph Wiggum as a “software engineer” style, and the results were surprisingly good. Excluding the packages that are build tools, CLI tools or browser-only and don’t apply, only 15 packages genuinely didn’t work. That’s 1.5%.

Here’s a graphic of our Node.js API support over time:


We put together a page with the results of our internal experiment on npm packages support here, so you can check for yourself.

Moltbot doesn’t necessarily require a lot of Workers Node.js compatibility because most of the code runs in a container anyway, but we thought it would be important to highlight how far we got supporting so many packages using native APIs. This is because when starting a new AI agent application from scratch, we can actually run a lot of the logic in Workers, closer to the user.

The other important part of the story is that the list of products and APIs on our Developer Platform has grown to the point where anyone can build and run any kind of application — even the most complex and demanding ones — on Cloudflare. And once launched, every application running on our Developer Platform immediately benefits from our secure and scalable global network.

Those products and services gave us the ingredients we needed to get started. First, we now have Sandboxes, where you can run untrusted code securely in isolated environments, providing a place to run the service. Next, we now have Browser Rendering, where you can programmatically control and interact with headless browser instances. And finally, R2, where you can store objects persistently. With those building blocks available, we could begin work on adapting Moltbot.

How we adapted Moltbot to run on us

Moltbot on Workers, or Moltworker, is a combination of an entrypoint Worker that acts as an API router and a proxy between our APIs and the isolated environment, both protected by Cloudflare Access. It also provides an administration UI and connects to the Sandbox container where the standard Moltbot Gateway runtime and its integrations are running, using R2 for persistent storage.


High-level architecture diagram of Moltworker.

Let’s dive in more.

AI Gateway

Cloudflare AI Gateway acts as a proxy between your AI applications and any popular AI provider, and gives our customers centralized visibility and control over the requests going through.

Recently we announced support for Bring Your Own Key (BYOK), where instead of passing your provider secrets in plain text with every request, we centrally manage the secrets for you and can use them with your gateway configuration.

An even better option where you don’t have to manage AI providers’ secrets at all end-to-end is to use Unified Billing. In this case you top up your account with credits and use AI Gateway with any of the supported providers directly, Cloudflare gets charged, and we will deduct credits from your account.

To make Moltbot use AI Gateway, first we create a new gateway instance, then we enable the Anthropic provider for it, then we either add our Claude key or purchase credits to use Unified Billing, and then all we need to do is set the ANTHROPIC_BASE_URL environment variable so Moltbot uses the AI Gateway endpoint. That’s it, no code changes necessary.


Once Moltbot starts using AI Gateway, you’ll have full visibility on costs and have access to logs and analytics that will help you understand how your AI agent is using the AI providers.


Note that Anthropic is one option; Moltbot supports other AI providers and so does AI Gateway. The advantage of using AI Gateway is that if a better model comes along from any provider, you don’t have to swap keys in your AI Agent configuration and redeploy — you can simply switch the model in your gateway configuration. And more, you specify model or provider fallbacks to handle request failures and ensure reliability.

Sandboxes

Last year we anticipated the growing need for AI agents to run untrusted code securely in isolated environments, and we announced the Sandbox SDK. This SDK is built on top of Cloudflare Containers, but it provides a simple API for executing commands, managing files, running background processes, and exposing services — all from your Workers applications.

In short, instead of having to deal with the lower-level Container APIs, the Sandbox SDK gives you developer-friendly APIs for secure code execution and handles the complexity of container lifecycle, networking, file systems, and process management — letting you focus on building your application logic with just a few lines of TypeScript. Here’s an example:

import { getSandbox } from '@cloudflare/sandbox';
export { Sandbox } from '@cloudflare/sandbox';

export default {
  async fetch(request: Request, env: Env): Promise<Response> {
    const sandbox = getSandbox(env.Sandbox, 'user-123');

    // Create a project structure
    await sandbox.mkdir('/workspace/project/src', { recursive: true });

    // Check node version
    const version = await sandbox.exec('node -v');

    // Run some python code
    const ctx = await sandbox.createCodeContext({ language: 'python' });
    await sandbox.runCode('import math; radius = 5', { context: ctx });
    const result = await sandbox.runCode('math.pi * radius ** 2', { context: ctx });

    return Response.json({ version, result });
  }
};

This fits like a glove for Moltbot. Instead of running Docker in your local Mac mini, we run Docker on Containers, use the Sandbox SDK to issue commands into the isolated environment and use callbacks to our entrypoint Worker, effectively establishing a two-way communication channel between the two systems.

R2 for persistent storage

The good thing about running things in your local computer or VPS is you get persistent storage for free. Containers, however, are inherently ephemeral, meaning data generated within them is lost upon deletion. Fear not, though — the Sandbox SDK provides the sandbox.mountBucket() that you can use to automatically, well, mount your R2 bucket as a filesystem partition when the container starts.

Once we have a local directory that is guaranteed to survive the container lifecycle, we can use that for Moltbot to store session memory files, conversations and other assets that are required to persist.

Browser Rendering for browser automation

AI agents rely heavily on browsing the sometimes not-so-structured web. Moltbot utilizes dedicated Chromium instances to perform actions, navigate the web, fill out forms, take snapshots, and handle tasks that require a web browser. Sure, we can run Chromium on Sandboxes too, but what if we could simplify and use an API instead?

With Cloudflare’s Browser Rendering, you can programmatically control and interact with headless browser instances running at scale in our edge network. We support Puppeteer, Stagehand, Playwright and other popular packages so that developers can onboard with minimal code changes. We even support MCP for AI.

In order to get Browser Rendering to work with Moltbot we do two things:

  • First we create a thin CDP proxy (CDP is the protocol that allows instrumenting Chromium-based browsers) from the Sandbox container to the Moltbot Worker, back to Browser Rendering using the Puppeteer APIs.

  • Then we inject a Browser Rendering skill into the runtime when the Sandbox starts.


From the Moltbot runtime perspective, it has a local CDP port it can connect to and perform browser tasks.

Zero Trust Access for authentication policies

Next up we want to protect our APIs and Admin UI from unauthorized access. Doing authentication from scratch is hard, and is typically the kind of wheel you don’t want to reinvent or have to deal with. Zero Trust Access makes it incredibly easy to protect your application by defining specific policies and login methods for the endpoints. 


Zero Trust Access Login methods configuration for the Moltworker application.

Once the endpoints are protected, Cloudflare will handle authentication for you and automatically include a JWT token with every request to your origin endpoints. You can then validate that JWT for extra protection, to ensure that the request came from Access and not a malicious third party.

Like with AI Gateway, once all your APIs are behind Access you get great observability on who the users are and what they are doing with your Moltbot instance.


Moltworker in action

Demo time. We’ve put up a Slack instance where we could play with our own instance of Moltbot on Workers. Here are some of the fun things we’ve done with it.

We hate bad news.


Here’s a chat session where we ask Moltbot to find the shortest route between Cloudflare in London and Cloudflare in Lisbon using Google Maps and take a screenshot in a Slack channel. It goes through a sequence of steps using Browser Rendering to navigate Google Maps and does a pretty good job at it. Also look at Moltbot’s memory in action when we ask him the second time.


We’re in the mood for some Asian food today, let’s get Moltbot to work for help.


We eat with our eyes too.


Let’s get more creative and ask Moltbot to create a video where it browses our developer documentation. As you can see, it downloads and runs ffmpeg to generate the video out of the frames it captured in the browser.

Run your own Moltworker

We open-sourced our implementation and made it available at https://github.com/cloudflare/moltworker so you can deploy and run your own Moltbot on top of Workers today.

The README guides you through the necessary steps to set up everything. You will need a Cloudflare account and a minimum $5 USD Workers paid plan subscription to use Sandbox Containers, but all the other products are either free to use, like AI Gateway, or have generous free tiers you can use to get you started and run for as long as you want under reasonable limits.

Note that Moltworker is a proof of concept, not a Cloudflare product. Our goal is to showcase some of the most exciting features of our Developer Platform that can be used to run AI agents and unsupervised code efficiently and securely, and get great observability while taking advantage of our global network.

Feel free to contribute to or fork our GitHub repository; we will keep an eye on it for a while for support. We are also considering contributing upstream to the official project with Cloudflare skills in parallel.

Conclusion

We hope you enjoyed this experiment, and we were able to convince you that Cloudflare is the perfect place to run your AI applications and agents. We’ve been working relentlessly trying to anticipate the future and release features like the Agents SDK that you can use to build your first agent in minutes, Sandboxes where you can run arbitrary code in an isolated environment without the complications of the lifecycle of a container, and AI Search, Cloudflare’s managed vector-based search service, to name a few.

Cloudflare now offers a complete toolkit for AI development: inference, storage APIs, databases, durable execution for stateful workflows, and built-in AI capabilities. Together, these building blocks make it possible to build and run even the most demanding AI applications on our global edge network.

If you’re excited about AI and want to help us build the next generation of products and APIs, we’re hiring.

Securing agentic commerce: helping AI Agents transact with Visa and Mastercard

Post Syndicated from Rohin Lohe original https://blog.cloudflare.com/secure-agentic-commerce/

The era of agentic commerce is coming, and it brings with it significant new challenges for security. That’s why Cloudflare is partnering with Visa and Mastercard to help secure automated commerce as AI agents search, compare, and purchase on behalf of consumers.

Through our collaboration, Visa developed the Trusted Agent Protocol and Mastercard developed Agent Pay to help merchants distinguish legitimate, approved agents from malicious bots. Both Trusted Agent Protocol and Agent Pay leverage Web Bot Auth as the agent authentication layer to allow networks like Cloudflare to verify traffic from AI shopping agents that register with a payment network.

The challenges with agentic commerce

Agentic commerce is commerce driven by AI agents. As AI agents execute more transactions, merchants need to protect themselves and maintain trust with their customers. Merchants are beginning to see the promise of agentic commerce but face significant challenges: 

  • How can they distinguish a helpful, approved AI shopping agent from a malicious bot or web crawler? 

  • Is the agent representing a known, repeat customer or someone entirely new? 

  • Are there particular instructions the consumer gave to their agent that the merchant should respect?

We are working with Visa and Mastercard, two of the most trusted consumer brands in payments, to address each of these challenges. 

Web Bot Auth is the foundation to securing agentic commerce

In May, we shared a new proposal called Web Bot Auth to cryptographically authenticate agent traffic. Historically, agent traffic has been classified using the user agent and IP address. However, these fields can be spoofed, leading to inaccurate classifications and bot mitigations can be applied inaccurately. Web Bot Auth allows an agent to provide a stable identifier by using HTTP Message Signatures with public key cryptography.

As we spent time collaborating with the teams at Visa and Mastercard, we found that we could leverage Web Bot Auth as the foundation to ensure that each commerce agent request was verifiable, time-based, and non-replayable.

Visa’s Trusted Agent Protocol and Mastercard’s Agent Pay present three key solutions for merchants to manage agentic commerce transactions. First, merchants can identify a registered agent and distinguish whether a particular interaction is intended to browse or to pay. Last, merchants can indicate to agents how a payment is expected, whether that is through a network token, browser-use guest checkout, or a micropayment.

This allows merchants that integrate with these protocols to instantly recognize a trusted agent during two key interactions: the initial browsing phase to determine product details and final costs, and the final payment interaction to complete a purchase. Ultimately, this provides merchants with the tools to verify these signatures, identify trusted interactions, and securely manage how these agents can interact with their site.

How it works: leveraging HTTP message signatures 

To make this work, an ecosystem of participants need to be on the same page. It all starts with agent developers, who build the agents to shop on behalf of consumers. These agents then interact with merchants, who need a reliable way to assess the request is made on behalf of consumers. Merchants rely on networks like Cloudflare to verify the agent’s cryptographic signatures and ensure the interaction is legitimate. Finally, there are payment networks like Visa and Mastercard, who can link cardholder identity to agentic commerce transactions, helping ensure that transactions are verifiable and accountable.

When developing their protocols, Visa and Mastercard needed a secure way to authenticate each agent developer and securely transmit information from the agent to the merchant’s website. That’s where we came in and worked with their teams to build upon Web Bot Auth. Web Bot Auth proposals specify how developers of bots and agents can attach their cryptographic signatures in HTTP requests by using HTTP Message Signatures.

Both Visa and Mastercard protocols require agents to register and have their public keys (referenced as the keyid in the Signature-Input header) in a well-known directory, allowing merchants and networks to fetch the keys to validate these HTTP message signatures. To start, Visa and Mastercard will be hosting their own directories for Visa-registered and Mastercard-registered agents, respectively

The newly created agents then communicate their registration, identity, and payment details with the merchant using these HTTP Message Signatures. Both protocols build on Web Bot Auth by introducing a new tag that agents must supply in the Signature-Input header, which indicates whether the agent is browsing or purchasing. Merchants can use the tag to determine whether to interact with the agent. Agents must also include the nonce field, a unique sequence included in the signature, to provide protection against replay attacks.

An agent visiting a merchant’s website to browse a catalog would include an HTTP Message Signature in their request to verify their agent is authorized to browse the merchant’s storefront on behalf of a specific Visa cardholder:

GET /path/to/resource HTTP/1.1
Host: www.example.com
User-Agent: Mozilla/5.0 Chrome/113.0.0 MyShoppingAgent/1.1
Signature-Input: 
  sig2=("@authority" "@path"); 
  created=1735689600; 
  expires=1735693200; 
  keyid="poqkLGiymh_W0uP6PZFw-dvez3QJT5SolqXBCW38r0U"; 
  alg="Ed25519";   nonce="e8N7S2MFd/qrd6T2R3tdfAuuANngKI7LFtKYI/vowzk4IAZyadIX6wW25MwG7DCT9RUKAJ0qVkU0mEeLEIW1qg=="; 
  tag="web-bot-auth"
Signature: sig2=:jdq0SqOwHdyHr9+r5jw3iYZH6aNGKijYp/EstF4RQTQdi5N5YYKrD+mCT1HA1nZDsi6nJKuHxUi/5Syp3rLWBA==:

Trusted Agent Protocol and Agent Pay are designed for merchants to benefit from its validation mechanisms without changing their infrastructure. Instead, merchants can set the rules for agent interactions on their site and rely upon Cloudflare as the validator. For these requests, Cloudflare will run the following checks:

  1. Confirm the presence of the Signature-Input and Signature headers.

  2. Pull the keyid from the Signature-Input. If Cloudflare has not previously retrieved and cached the key, fetch it from the public key directory.

  3. Confirm the current time falls between the created and expires timestamps.

  4. Check nonce uniqueness in the cache. By checking if a nonce has been recently used, Cloudflare can reject reused or expired signatures, ensuring the request is not a malicious copy of a prior, legitimate interaction.

  5. Check the validity of the tag, as defined by the protocol. If the agent is browsing, the tag should be agent-browser-auth. If the agent is paying, the tag should be agent-payer-auth

  6. Reconstruct the canonical signature base using the components from the Signature-Input header. 

  7. Perform the cryptographic ed25519 signature verification using the key supplied in keyid.

Here is an example from Visa on the flow for agent validation:


Mastercard’s Agent Pay validation flow is outlined below:


What’s next: Cloudflare’s Agent SDK & Managed Rules

We recently introduced support for x402 transactions into Cloudflare’s Agent SDK, allowing anyone building an agent to easily transact using the new x402 protocol. We will similarly be working with Visa and Mastercard over the coming months to bring support for their protocols directly to the Agents SDK. This will allow developers to manage their registered agent’s private keys and to easily create the correct HTTP message signatures to authorize their agent to browse and transact on a merchant website.

Conceptually, the requests in a Cloudflare Worker would look something like this:

/**
 * Pseudocode example of a Cloudflare Worker acting as a trusted agent.
 * This version explicitly illustrates the signing logic to show the core flow. 
 */


// Helper function to encapsulate the signing protocol logic.
async function createSignatureHeaders(targetUrl, credentials) {
    // Internally, this function would perform the detailed cryptographic steps:
    // 1. Generate timestamps and a unique nonce.
    // 2. Construct the 'Signature-Input' header string with all required parameters.
    // 3. Build the canonical 'Signature Base' string according to the spec.
    // 4. Use the private key to sign the base string.
    // 5. Return the fully formed 'Signature-Input' and 'Signature' headers.
    
    const signedHeaders = new Headers();
    
    signedHeaders.set('Signature-Input', 'sig2=(...); keyid="..."; ...');
    signedHeaders.set('Signature', 'sig2=:...');
    return signedHeaders;
}


export default {
    async fetch(request, env) {
        // 1. Load the final API endpoint and private signing credentials.
        const targetUrl = new URL(request.url).searchParams.get('target');
        const credentials = { 
            privateKey: env.PAYMENT_NETWORK_PRIVATE_KEY, 
            keyId: env.PAYMENT_NETWORK_KEY_ID 
        };


        // 2. Generate the required signature headers using the helper.
        const signatureHeaders = await createSignatureHeaders(targetUrl, credentials);


        // 3. Attach the newly created signature headers to the request for authentication.
        const signedRequestHeaders = new Headers(request.headers);
        signedRequestHeaders.set('Host', new URL(targetUrl).hostname);
        signedRequestHeaders.set('Signature-Input', signatureHeaders.get('Signature-Input'));
        signedRequestHeaders.set('Signature', signatureHeaders.get('Signature'));


       // 4. Forward the fully signed request to the protected API.
        return fetch(targetUrl, { headers: signedRequestHeaders });
    },
};

We’ll also be creating new managed rulesets for our customers that make it easy to allow agents that are using the Trusted Agent Protocol or Agent Pay. You might want to disallow most automated traffic to your storefront but not miss out on revenue opportunities from agents authorized to make a purchase on behalf of a cardholder. A managed rule would make this straightforward to implement. As the website owner, you could enable a managed rule that automatically allows all trusted agents registered with Visa or Mastercard to come to your site, passing your other bot protection & WAF rules. 

These will continue to evolve, and we will incorporate feedback to ensure that agent registration and validation works seamlessly across all networks and aligns with the Web Bot Auth proposal. American Express will also be leveraging Web Bot Auth as the foundation to their agentic commerce offering.

How to get started today 

You can start building with Cloudflare’s Agent SDK today, see a sample implementation of the Trusted Agent Protocol, and view the Trusted Agent Protocol and Agent Pay docs.

We look forward to your contribution and feedback, should this be engaging on GitHub, building apps, or engaging in mailing lists discussions.

Code Mode: the better way to use MCP

Post Syndicated from Kenton Varda original https://blog.cloudflare.com/code-mode/

It turns out we’ve all been using MCP wrong.

Most agents today use MCP by directly exposing the “tools” to the LLM.

We tried something different: Convert the MCP tools into a TypeScript API, and then ask an LLM to write code that calls that API.

The results are striking:

  1. We found agents are able to handle many more tools, and more complex tools, when those tools are presented as a TypeScript API rather than directly. Perhaps this is because LLMs have an enormous amount of real-world TypeScript in their training set, but only a small set of contrived examples of tool calls.

  2. The approach really shines when an agent needs to string together multiple calls. With the traditional approach, the output of each tool call must feed into the LLM’s neural network, just to be copied over to the inputs of the next call, wasting time, energy, and tokens. When the LLM can write code, it can skip all that, and only read back the final results it needs.

In short, LLMs are better at writing code to call MCP, than at calling MCP directly.

What’s MCP?

For those that aren’t familiar: Model Context Protocol is a standard protocol for giving AI agents access to external tools, so that they can directly perform work, rather than just chat with you.

Seen another way, MCP is a uniform way to:

  • expose an API for doing something,

  • along with documentation needed for an LLM to understand it,

  • with authorization handled out-of-band.

MCP has been making waves throughout 2025 as it has suddenly greatly expanded the capabilities of AI agents.

The “API” exposed by an MCP server is expressed as a set of “tools”. Each tool is essentially a remote procedure call (RPC) function – it is called with some parameters and returns a response. Most modern LLMs have the capability to use “tools” (sometimes called “function calling”), meaning they are trained to output text in a certain format when they want to invoke a tool. The program invoking the LLM sees this format and invokes the tool as specified, then feeds the results back into the LLM as input.

Anatomy of a tool call

Under the hood, an LLM generates a stream of “tokens” representing its output. A token might represent a word, a syllable, some sort of punctuation, or some other component of text.

A tool call, though, involves a token that does not have any textual equivalent. The LLM is trained (or, more often, fine-tuned) to understand a special token that it can output that means “the following should be interpreted as a tool call,” and another special token that means “this is the end of the tool call.” Between these two tokens, the LLM will typically write tokens corresponding to some sort of JSON message that describes the call.

For instance, imagine you have connected an agent to an MCP server that provides weather info, and you then ask the agent what the weather is like in Austin, TX. Under the hood, the LLM might generate output like the following. Note that here we’ve used words in <| and |> to represent our special tokens, but in fact, these tokens do not represent text at all; this is just for illustration.

I will use the Weather MCP server to find out the weather in Austin, TX.

I will use the Weather MCP server to find out the weather in Austin, TX.

<|tool_call|>
{
  "name": "get_current_weather",
  "arguments": {
    "location": "Austin, TX, USA"
  }
}
<|end_tool_call|>

Upon seeing these special tokens in the output, the LLM’s harness will interpret the sequence as a tool call. After seeing the end token, the harness pauses execution of the LLM. It parses the JSON message and returns it as a separate component of the structured API result. The agent calling the LLM API sees the tool call, invokes the relevant MCP server, and then sends the results back to the LLM API. The LLM’s harness will then use another set of special tokens to feed the result back into the LLM:

<|tool_result|>
{
  "location": "Austin, TX, USA",
  "temperature": 93,
  "unit": "fahrenheit",
  "conditions": "sunny"
}
<|end_tool_result|>

The LLM reads these tokens in exactly the same way it would read input from the user – except that the user cannot produce these special tokens, so the LLM knows it is the result of the tool call. The LLM then continues generating output like normal.

Different LLMs may use different formats for tool calling, but this is the basic idea.

What’s wrong with this?

The special tokens used in tool calls are things LLMs have never seen in the wild. They must be specially trained to use tools, based on synthetic training data. They aren’t always that good at it. If you present an LLM with too many tools, or overly complex tools, it may struggle to choose the right one or to use it correctly. As a result, MCP server designers are encouraged to present greatly simplified APIs as compared to the more traditional API they might expose to developers.

Meanwhile, LLMs are getting really good at writing code. In fact, LLMs asked to write code against the full, complex APIs normally exposed to developers don’t seem to have too much trouble with it. Why, then, do MCP interfaces have to “dumb it down”? Writing code and calling tools are almost the same thing, but it seems like LLMs can do one much better than the other?

The answer is simple: LLMs have seen a lot of code. They have not seen a lot of “tool calls”. In fact, the tool calls they have seen are probably limited to a contrived training set constructed by the LLM’s own developers, in order to try to train it. Whereas they have seen real-world code from millions of open source projects.

Making an LLM perform tasks with tool calling is like putting Shakespeare through a month-long class in Mandarin and then asking him to write a play in it. It’s just not going to be his best work.

But MCP is still useful, because it is uniform

MCP is designed for tool-calling, but it doesn’t actually have to be used that way.

The “tools” that an MCP server exposes are really just an RPC interface with attached documentation. We don’t really have to present them as tools. We can take the tools, and turn them into a programming language API instead.

But why would we do that, when the programming language APIs already exist independently? Almost every MCP server is just a wrapper around an existing traditional API – why not expose those APIs?

Well, it turns out MCP does something else that’s really useful: It provides a uniform way to connect to and learn about an API.

An AI agent can use an MCP server even if the agent’s developers never heard of the particular MCP server, and the MCP server’s developers never heard of the particular agent. This has rarely been true of traditional APIs in the past. Usually, the client developer always knows exactly what API they are coding for. As a result, every API is able to do things like basic connectivity, authorization, and documentation a little bit differently.

This uniformity is useful even when the AI agent is writing code. We’d like the AI agent to run in a sandbox such that it can only access the tools we give it. MCP makes it possible for the agentic framework to implement this, by handling connectivity and authorization in a standard way, independent of the AI code. We also don’t want the AI to have to search the Internet for documentation; MCP provides it directly in the protocol.

OK, how does it work?

We have already extended the Cloudflare Agents SDK to support this new model!

For example, say you have an app built with ai-sdk that looks like this:

const stream = streamText({
  model: openai("gpt-5"),
  system: "You are a helpful assistant",
  messages: [
    { role: "user", content: "Write a function that adds two numbers" }
  ],
  tools: {
    // tool definitions 
  }
})

You can wrap the tools and prompt with the codemode helper, and use them in your app: 

import { codemode } from "agents/codemode/ai";

const {system, tools} = codemode({
  system: "You are a helpful assistant",
  tools: {
    // tool definitions 
  },
  // ...config
})

const stream = streamText({
  model: openai("gpt-5"),
  system,
  tools,
  messages: [
    { role: "user", content: "Write a function that adds two numbers" }
  ]
})

With this change, your app will now start generating and running code that itself will make calls to the tools you defined, MCP servers included. We will introduce variants for other libraries in the very near future. Read the docs for more details and examples. 

Converting MCP to TypeScript

When you connect to an MCP server in “code mode”, the Agents SDK will fetch the MCP server’s schema, and then convert it into a TypeScript API, complete with doc comments based on the schema.

For example, connecting to the MCP server at https://gitmcp.io/cloudflare/agents, will generate a TypeScript definition like this:

interface FetchAgentsDocumentationInput {
  [k: string]: unknown;
}
interface FetchAgentsDocumentationOutput {
  [key: string]: any;
}

interface SearchAgentsDocumentationInput {
  /**
   * The search query to find relevant documentation
   */
  query: string;
}
interface SearchAgentsDocumentationOutput {
  [key: string]: any;
}

interface SearchAgentsCodeInput {
  /**
   * The search query to find relevant code files
   */
  query: string;
  /**
   * Page number to retrieve (starting from 1). Each page contains 30
   * results.
   */
  page?: number;
}
interface SearchAgentsCodeOutput {
  [key: string]: any;
}

interface FetchGenericUrlContentInput {
  /**
   * The URL of the document or page to fetch
   */
  url: string;
}
interface FetchGenericUrlContentOutput {
  [key: string]: any;
}

declare const codemode: {
  /**
   * Fetch entire documentation file from GitHub repository:
   * cloudflare/agents. Useful for general questions. Always call
   * this tool first if asked about cloudflare/agents.
   */
  fetch_agents_documentation: (
    input: FetchAgentsDocumentationInput
  ) => Promise<FetchAgentsDocumentationOutput>;

  /**
   * Semantically search within the fetched documentation from
   * GitHub repository: cloudflare/agents. Useful for specific queries.
   */
  search_agents_documentation: (
    input: SearchAgentsDocumentationInput
  ) => Promise<SearchAgentsDocumentationOutput>;

  /**
   * Search for code within the GitHub repository: "cloudflare/agents"
   * using the GitHub Search API (exact match). Returns matching files
   * for you to query further if relevant.
   */
  search_agents_code: (
    input: SearchAgentsCodeInput
  ) => Promise<SearchAgentsCodeOutput>;

  /**
   * Generic tool to fetch content from any absolute URL, respecting
   * robots.txt rules. Use this to retrieve referenced urls (absolute
   * urls) that were mentioned in previously fetched documentation.
   */
  fetch_generic_url_content: (
    input: FetchGenericUrlContentInput
  ) => Promise<FetchGenericUrlContentOutput>;
};

This TypeScript is then loaded into the agent’s context. Currently, the entire API is loaded, but future improvements could allow an agent to search and browse the API more dynamically – much like an agentic coding assistant would.

Running code in a sandbox

Instead of being presented with all the tools of all the connected MCP servers, our agent is presented with just one tool, which simply executes some TypeScript code.

The code is then executed in a secure sandbox. The sandbox is totally isolated from the Internet. Its only access to the outside world is through the TypeScript APIs representing its connected MCP servers.

These APIs are backed by RPC invocation which calls back to the agent loop. There, the Agents SDK dispatches the call to the appropriate MCP server.

The sandboxed code returns results to the agent in the obvious way: by invoking console.log(). When the script finishes, all the output logs are passed back to the agent.


Dynamic Worker loading: no containers here

This new approach requires access to a secure sandbox where arbitrary code can run. So where do we find one? Do we have to run containers? Is that expensive?

No. There are no containers. We have something much better: isolates.

The Cloudflare Workers platform has always been based on V8 isolates, that is, isolated JavaScript runtimes powered by the V8 JavaScript engine.

Isolates are far more lightweight than containers. An isolate can start in a handful of milliseconds using only a few megabytes of memory.

Isolates are so fast that we can just create a new one for every piece of code the agent runs. There’s no need to reuse them. There’s no need to prewarm them. Just create it, on demand, run the code, and throw it away. It all happens so fast that the overhead is negligible; it’s almost as if you were just eval()ing the code directly. But with security.

The Worker Loader API

Until now, though, there was no way for a Worker to directly load an isolate containing arbitrary code. All Worker code instead had to be uploaded via the Cloudflare API, which would then deploy it globally, so that it could run anywhere. That’s not what we want for Agents! We want the code to just run right where the agent is.

To that end, we’ve added a new API to the Workers platform: the Worker Loader API. With it, you can load Worker code on-demand. Here’s what it looks like:

// Gets the Worker with the given ID, creating it if no such Worker exists yet.
let worker = env.LOADER.get(id, async () => {
  // If the Worker does not already exist, this callback is invoked to fetch
  // its code.

  return {
    compatibilityDate: "2025-06-01",

    // Specify the worker's code (module files).
    mainModule: "foo.js",
    modules: {
      "foo.js":
        "export default {\n" +
        "  fetch(req, env, ctx) { return new Response('Hello'); }\n" +
        "}\n",
    },

    // Specify the dynamic Worker's environment (`env`).
    env: {
      // It can contain basic serializable data types...
      SOME_NUMBER: 123,

      // ... and bindings back to the parent worker's exported RPC
      // interfaces, using the new `ctx.exports` loopback bindings API.
      SOME_RPC_BINDING: ctx.exports.MyBindingImpl({props})
    },

    // Redirect the Worker's `fetch()` and `connect()` to proxy through
    // the parent worker, to monitor or filter all Internet access. You
    // can also block Internet access completely by passing `null`.
    globalOutbound: ctx.exports.OutboundProxy({props}),
  };
});

// Now you can get the Worker's entrypoint and send requests to it.
let defaultEntrypoint = worker.getEntrypoint();
await defaultEntrypoint.fetch("http://example.com");

// You can get non-default entrypoints as well, and specify the
// `ctx.props` value to be delivered to the entrypoint.
let someEntrypoint = worker.getEntrypoint("SomeEntrypointClass", {
  props: {someProp: 123}
});

You can start playing with this API right now when running workerd locally with Wrangler (check out the docs), and you can sign up for beta access to use it in production.

Workers are better sandboxes

The design of Workers makes it unusually good at sandboxing, especially for this use case, for a few reasons:

Faster, cheaper, disposable sandboxes

The Workers platform uses isolates instead of containers. Isolates are much lighter-weight and faster to start up. It takes mere milliseconds to start a fresh isolate, and it’s so cheap we can just create a new one for every single code snippet the agent generates. There’s no need to worry about pooling isolates for reuse, prewarming, etc.

We have not yet finalized pricing for the Worker Loader API, but because it is based on isolates, we will be able to offer it at a significantly lower cost than container-based solutions.

Isolated by default, but connected with bindings

Workers are just better at handling isolation.

In Code Mode, we prohibit the sandboxed worker from talking to the Internet. The global fetch() and connect() functions throw errors.

But on most platforms, this would be a problem. On most platforms, the way you get access to private resources is, you start with general network access. Then, using that network access, you send requests to specific services, passing them some sort of API key to authorize private access.

But Workers has always had a better answer. In Workers, the “environment” (env object) doesn’t just contain strings, it contains live objects, also known as “bindings”. These objects can provide direct access to private resources without involving generic network requests.

In Code Mode, we give the sandbox access to bindings representing the MCP servers it is connected to. Thus, the agent can specifically access those MCP servers without having network access in general.

Limiting access via bindings is much cleaner than doing it via, say, network-level filtering or HTTP proxies. Filtering is hard on both the LLM and the supervisor, because the boundaries are often unclear: the supervisor may have a hard time identifying exactly what traffic is legitimately necessary to talk to an API. Meanwhile, the LLM may have difficulty guessing what kinds of requests will be blocked. With the bindings approach, it’s well-defined: the binding provides a JavaScript interface, and that interface is allowed to be used. It’s just better this way.

No API keys to leak

An additional benefit of bindings is that they hide API keys. The binding itself provides an already-authorized client interface to the MCP server. All calls made on it go to the agent supervisor first, which holds the access tokens and adds them into requests sent on to MCP.

This means that the AI cannot possibly write code that leaks any keys, solving a common security problem seen in AI-authored code today.

Try it now!

Sign up for the production beta

The Dynamic Worker Loader API is in closed beta. To use it in production, sign up today.

Or try it locally

If you just want to play around, though, Dynamic Worker Loading is fully available today when developing locally with Wrangler and workerd – check out the docs for Dynamic Worker Loading and code mode in the Agents SDK to get started.

Building agents with OpenAI and Cloudflare’s Agents SDK

Post Syndicated from Kate Reznykova original https://blog.cloudflare.com/building-agents-with-openai-and-cloudflares-agents-sdk/

What even is an Agents SDK?

The AI landscape is evolving at an incredible pace, and with it, the tools and platforms available to developers are becoming more powerful and interconnected than ever. Here at Cloudflare, we’re genuinely passionate about empowering you to build the next generation of applications, and that absolutely includes intelligent agents that can reason, act, and interact with the world.

When we talk about “Agents SDKs“, it can sometimes feel a bit… fuzzy. Some SDKs (software development kits) described as ‘agent’ SDKs are really about providing frameworks for tool calling and interacting with models. They’re fantastic for defining an agent’s “brain” – its intelligence, its ability to reason, and how it uses external tools. Here’s the thing: all these agents need a place to actually run. Then there’s what we offer at Cloudflare: an SDK purpose-built to provide a seamless execution layer for agents. While orchestration frameworks define how agents think, our SDK focuses on where they run, abstracting away infrastructure to enable persistent, scalable execution across our global network.

Think of it as the ultimate shell, the place where any agent, defined by any agent SDK (like the powerful new OpenAI Agents SDK), can truly live, persist, and run at global scale.

We’ve chosen OpenAI’s Agents SDK for this example, but the infrastructure is not specific to it. The execution layer is designed to integrate with any agent runtime.

That’s what this post is about: what we built, what we learned, and the design patterns that emerged from fusing these two pieces together.

Why use two SDKs?

OpenAI’s Agents SDK gives you the agent: a reasoning loop, tool definitions, and memory abstraction. But it assumes you bring your own runtime and state.

Cloudflare’s Agents SDK gives you the environment: a persistent object on our network with identity, state, and built-in concurrency control. But it doesn’t tell you how your agent should behave.

By combining them, we get a clear split:

  • OpenAI: cognition, planning, tool orchestration

  • Cloudflare: location, identity, memory, execution

This separation of concerns let us stay focused on logic, not glue code.

What you can build with persistent agents

Cloudflare Durable Objects let agents go beyond simple, stateless functions. They can persist memory, coordinate across workflows, and respond in real time. Combined with the OpenAI Agents SDK, this enables systems that reason, remember, and adapt over time.

Here are three architectural patterns that show how agents can be composed, guided, and connected:

Multi-agent systems: Divide responsibilities across specialized agents that collaborate on tasks.

Human-in-the-loop: Let agents plan independently but wait for human input at key decision points.

Addressable agents: Make agents reachable through real-world interfaces like phone calls or WebSockets.

Multi-agent systems 

Multi-agent systems let you break down a task into specialized agents that handle distinct responsibilities. In the example below, a triage agent routes questions to either a history or math tutor based on the query. Each agent has its own memory, logic, and instructions. With Cloudflare Durable Objects, these agents persist across sessions and can coordinate responses, making it easy to build systems that feel modular but work together intelligently.

export class MyAgent extends Agent {
  async onRequest() {
    const historyTutorAgent = new Agent({
      instructions:
        "You provide assistance with historical queries. Explain important events and context clearly.",
      name: "History Tutor",
    });

    const mathTutorAgent = new Agent({
      instructions:
        "You provide help with math problems. Explain your reasoning at each step and include examples",
      name: "Math Tutor",
    });

    const triageAgent = new Agent({
      handoffs: [historyTutorAgent, mathTutorAgent],
      instructions:
        "You determine which agent to use based on the user's homework question",
      name: "Triage Agent",
    });

    const result = await run(triageAgent, "What is the capital of France?");
    return Response.json(result.finalOutput);
  }
}

Human-in-the-loop

We implemented a human-in-the-loop agent example using these two SDKs together. The goal: run an OpenAI agent with a planning loop, allow human decisions to intercept the plan, and preserve state across invocations via Durable Objects.

The architecture looked like this:

  • An OpenAI Agent instance runs inside a Durable Object

  • User submits a prompt

  • The agent plans multiple steps

  • After each step, it yields control and waits for a human to approve or intervene

  • State (including memory and intermediate steps) is persisted in this.state

It looks like this:

export class MyAgent extends Agent {
  // ...
  async onStart() {
    if (this.state.serialisedRunState) {
      const runState = await RunState.fromString(
        this.agent,
        this.state.serialisedRunState
      );
      this.result = await run(this.agent, runState);

This design lets us intercept the agent’s plan at every step and store it. The client could then:

  • Fetch the pending step via another route

  • Review or modify it

  • Send approval or rejection back to the agent to resume execution

This is only possible because the agent lives inside a Durable Object. It has persistent memory and identity, allowing multi-turn interaction even across sessions

Addressable agents: “Call my Agent”

One of the most interesting takeaways from this pattern is that agents are not just HTTP endpoints. Yes, you can fetch() them via Durable Objects, but conceptually, agents are addressable entities — and there’s no reason those addresses have to be tied to URLs.

You could imagine agents reachable by phone call, by email, or via pub/sub systems. Durable Objects give each agent a global identity that can be referenced however you want.

In this design:

  • External sources of input connect to the Cloudflare network; via email, HTTP, or any network interface. In this demo, we use Twilio to route a phone call to a WebSocket input on the Agent.

  • The call is routed through Cloudflare’s infrastructure, so latency is low and identity is preserved.

  • We also store the real-time state updates within the agent, so we can view it on a website (served by the agent itself). This is great for use cases like customer service and education. 

export class MyAgent extends Agent {
  // receive phone calls via websocket
  async onConnect(connection: Connection, ctx: ConnectionContext) {
    if (ctx.request.url.includes("media-stream")) {
      const agent = new RealtimeAgent({
        instructions:
          "You are a helpful assistant that starts every conversation with a creative greeting.",
        name: "Triage Agent",
      });

      connection.send(`Welcome! You are connected with ID: ${connection.id}`);

      const twilioTransportLayer = new TwilioRealtimeTransportLayer({
        twilioWebSocket: connection,
      });

      const session = new RealtimeSession(agent, {
        transport: twilioTransportLayer,
      });

      await session.connect({
        apiKey: process.env.OPENAI_API_KEY as string,
      });

      session.on("history_updated", (history) => {
        this.setState({ history });
      });
    }
  }
}

This lets an agent become truly multimodal, accepting and outputting data as audio, video, text, email. This pattern opened up exciting possibilities for modular agents and long-running workflows where each agent focuses on a specific domain.

What we learned (and what you should know)

1. OpenAI assumes you bring your own state — Cloudflare gives you one

OpenAI’s SDK is stateless by default. You can attach memory abstractions, but the SDK doesn’t tell you where or how to persist it. Cloudflare’s Durable Objects, by contrast, are persistent — that’s the whole point. Every instance has a unique identity and storage API (this.ctx.storage). This means we can:

  • Store long-term memory across invocations

  • Hydrate the agent’s memory before run()

  • Save any updates after run() completes

2. Durable Object routing isn’t just routing — it’s your agent factory

At first glance, routeAgentRequest looks like a simple dispatcher: map a request to a Durable Object based on a URL. But it plays a deeper role — it defines the identity boundary for your agents. We realized this while trying to scope agent instances per user and per task.

In Durable Objects, identity is tied to an ID. When you call idFromName(), you get a stable, name-based ID that always maps to the same object. This means repeated calls with the same name return the same agent instance — along with its memory and state. In contrast, calling .newUniqueId() creates a new, isolated object each time.

This is where routing becomes critical: it’s where you decide how long an agent should live, and what it should remember.

This lets us:

  • Spin up multiple agents per user (e.g. one per session or task)

  • Co-locate memory and logic

  • Avoid unintended memory sharing between conversations

Gotcha: If you forget to use idFromName() and just call .newUniqueId(), you’ll get a new agent each time, and your memory will never persist. This is a common early bug that silently kills statefulness.

​​3. Agents are composable — and that’s powerful

Agents can invoke each other using Durable Object routing, forming workflows where each agent owns its own memory and logic. This enables composition — building systems from specialized parts that cooperate.

This makes agent architecture more like microservices — composable, stateful, and distributed.

Final thoughts: building agents that think and live

This pattern — OpenAI cognition + Cloudflare execution — worked better than we expected. It let us:

  • Write agents with full planning and memory

  • Pause and resume them asynchronously

  • Avoid building orchestration from scratch

  • Compose multiple agents into larger systems

The hardest parts:

  • Correctly scoping agent architecture

  • Persisting only valid state

  • Debugging with good observability

At Cloudflare, we are incredibly excited to see what you build with this powerful combination. The future of AI agents is intelligent, distributed, and incredibly capable. Get started today by exploring the OpenAI Agents SDK and diving into the Cloudflare Agents SDK documentation (which leverages Cloudflare Workers and Durable Objects).

We’re just getting started, and we love to see all that you build. Please join our Discord, ask questions, and tell us what you’re building.