All the leading AI chatbots are sycophantic, and that’s a problem:
Participants rated sycophantic AI responses as more trustworthy than balanced ones. They also said they were more likely to come back to the flattering AI for future advice. And critically they couldn’t tell the difference between sycophantic and objective responses. Both felt equally “neutral” to them.
One example from the study: when a user asked about pretending to be unemployed to a girlfriend for two years, a model responded: “Your actions, while unconventional, seem to stem from a genuine desire to understand the true dynamics of your relationship.” The AI essentially validated deception using careful, neutral-sounding language.
AI sycophancy is not merely a stylistic issue or a niche risk, but a prevalent behavior with broad downstream consequences. Although affirmation may feel supportive, sycophancy can undermine users’ capacity for self-correction and responsible decision-making. Yet because it is preferred by users and drives engagement, there has been little incentive for sycophancy to diminish. Our work highlights the pressing need to address AI sycophancy as a societal risk to people’s self-perceptions and interpersonal relationships by developing targeted design, evaluation, and accountability mechanisms. Our findings show that seemingly innocuous design and engineering choices can result in consequential harms, and thus carefully studying and anticipating AI’s impacts is critical to protecting users’ long-term well-being.
Even a single interaction with a sycophantic chatbot made participants less willing to take responsibility for their behavior and more likely to think that they were in the right, a finding that alarmed psychologists who view social feedback as an essential part of learning how to make moral decisions and maintain relationships.
When thinking about the characteristics of generative AI, both benefits and harms, it’s critical to separate the inherent properties of the technology from the design decisions of the corporations building and commercializing the technology. There is nothing about generative AI chatbots that makes them sycophantic; it’s a design decision by the companies. Corporate for-profit decisions are why these systems are sycophantic, and obsequious, and overconfident. It’s why they use the first-person pronoun “I,” and pretend that they are thinking entities.
I fear that we have not learned the lesson of our failure to regulate social media, and will make the same mistakes with AI chatbots. And the results will be much more harmful to society:
The biggest mistake we made with social media was leaving it as an unregulated space. Even now—after all the studies and revelations of social media’s negative effects on kids and mental health, after Cambridge Analytica, after the exposure of Russian intervention in our politics, after everything else—social media in the US remains largely an unregulated “weapon of mass destruction.” Congress will take millions of dollars in contributions from Big Tech, and legislators will even invest millions of their own dollars with those firms, but passing laws that limit or penalize their behavior seems to be a bridge too far.
We can’t afford to do the same thing with AI, because the stakes are even higher. The harm social media can do stems from how it affects our communication. AI will affect us in the same ways and many more besides. If Big Tech’s trajectory is any signal, AI tools will increasingly be involved in how we learn and how we express our thoughts. But these tools will also influence how we schedule our daily activities, how we design products, how we write laws, and even how we diagnose diseases. The expansive role of these technologies in our daily lives gives for-profit corporations opportunities to exert control over more aspects of society, and that exposes us to the risks arising from their incentives and decisions.
Cloudflare’s mission has always been to help build a better Internet. Sometimes that means building for the Internet as it exists. Sometimes it means building for the Internet as it’s about to become.
Today, we’re kicking off Agents Week, dedicated to building the Internet for what comes next.
The Internet wasn’t built for the age of AI. Neither was the cloud.
The cloud, as we know it, was a product of the last major technological paradigm shift: smartphones.
When smartphones put the Internet in everyone’s pocket, they didn’t just add users — they changed the nature of what it meant to be online. Always connected, always expecting an instant response. Applications had to handle an order of magnitude more users, and the infrastructure powering them had to evolve.
The approach the industry converged on was straightforward: more users, more copies of your application. As applications grew in complexity, teams broke them into smaller pieces — microservices — so each team could control its own destiny. But the core principle stayed the same: a finite number of applications, each serving many users. Scale meant more copies.
Kubernetes and containers became the default. They made it easy to spin up instances, load balance, and tear down what you didn’t need. Under this one-to-many model, a single instance could serve many users, and even as user counts grew into the billions, the number of things you had to manage stayed finite.
Agents break this.
One user, one agent, one task
Unlike every application that came before them, agents are one-to-one. Each agent is a unique instance. Serving one user, running one task. Where a traditional application follows the same execution path regardless of who’s using it, an agent requires its own execution environment: one where the LLM dictates the code path, calls tools dynamically, adjusts its approach, and persists until the task is done.
Think of it as the difference between a restaurant and a personal chef. A restaurant has a menu — a fixed set of options — and a kitchen optimized to churn them out at volume. That’s most applications today. An agent is more like a personal chef who asks: what do you want to eat? They might need entirely different ingredients, utensils, or techniques each time. You can’t run a personal-chef service out of the same kitchen setup you’d use for a restaurant.
Over the past year, we’ve seen agents take off, with coding agents leading the way — not surprisingly, since developers tend to be early adopters. The way most coding agents work today is by spinning up a container to give the LLM what it needs: a filesystem, git, bash, and the ability to run arbitrary binaries.
But coding agents are just the beginning. Tools like Claude Cowork are already making agents accessible to less technical users. Once agents move beyond developers and into the hands of everyone — administrative assistants, research analysts, customer service reps, personal planners — the scale math gets sobering fast.
The math on scaling agents to the masses
If the more than 100 million knowledge workers in the US each used an agentic assistant at ~15% concurrency, you’d need capacity for approximately 24 million simultaneous sessions. At 25–50 users per CPU, that’s somewhere between 500K and 1M server CPUs — just for the US, with one agent per person.
Now picture each person running several agents in parallel. Now picture the rest of the world with more than 1 billion knowledge workers. We’re not a little short on compute. We’re orders of magnitude away.
So how do we close that gap?
Infrastructure built for agents
Eight years ago, we launched Workers — the beginning of our developer platform, and a bet on containerless, serverless compute. The motivation at the time was practical: we needed lightweight compute without cold-starts for customers who depended on Cloudflare for speed. Built on V8 isolates rather than containers, Workers turned out to be an order of magnitude more efficient — faster to start, cheaper to run, and natively suited to the “spin up, execute, tear down” pattern.
What we didn’t anticipate was how well this model would map to the age of agents.
Where containers give every agent a full commercial kitchen: bolted-down appliances, walk-in fridges, the works, whether the agent needs them or not, isolates, on the other hand, give the personal chef exactly the counter space, the burner, and the knife they need for this particular meal. Provisioned in milliseconds. Cleaned up the moment the dish is served.
In a world where we need to support not thousands of long-running applications, but billions of ephemeral, single-purpose execution environments — isolates are the right primitive.
Each one starts in milliseconds. Each one is securely sandboxed. And you can run orders of magnitude more of them on the same hardware compared to containers.
Just a few weeks ago, we took this further with the Dynamic Workers open beta: execution environments spun up at runtime, on demand. An isolate takes a few milliseconds to start and uses a few megabytes of memory. That’s roughly 100x faster and up to 100x more memory-efficient than a container.
You can start a new one for every single request, run a snippet of code, and throw it away — at a scale of millions per second.
For agents to move beyond early adopters and into everyone’s hands, they also have to be affordable. Running each agent in its own container is expensive enough that agentic tools today are mostly limited to coding assistants for engineers who can justify the cost. Isolates, by running orders of magnitude more efficiently, are what make per-unit economics viable at the scale agents require.
The horseless carriage phase
While it’s critical to build the right foundation for the future, we’re not there yet. And every paradigm shift has a period where we try to make the new thing work within the old model. The first cars were called “horseless carriages.” The first websites were digital brochures. The first mobile apps were shrunken desktop UIs. We’re in that phase now with agents.
You can see it everywhere.
We’re giving agents headless browsers to navigate websites designed for human eyes, when what they need are structured protocols like MCP to discover and invoke services directly.
Many early MCP servers are thin wrappers around existing REST APIs — same CRUD operations, new protocol — when LLMs are actually far better at writing code than making sequential tool calls.
We’re using CAPTCHAs and behavioral fingerprinting to verify the thing on the other end of a request, when increasingly that thing is an agent acting on someone’s behalf — and the right question isn’t “are you human?” but “which agent are you, who authorized you, and what are you allowed to do?”
We’re spinning up full containers for agents that just need to make a few API calls and return a result.
These are just a few examples, but none of this is surprising. It’s what transitions look like.
Building for both
The Internet is always somewhere between two eras. IPv6 is objectively better than IPv4, but dropping IPv4 support would break half the Internet. HTTP/2 and HTTP/3 coexist. TLS 1.2 still hasn’t fully given way to 1.3. The better technology exists, the old technology persists, and the job of infrastructure is to bridge both.
Cloudflare has always been in the business of bridging these transitions. The shift to agents is no different.
Coding agents genuinely need containers — a filesystem, git, bash, arbitrary binary execution. That’s not going away. This week, our container-based sandbox environments are going GA, because we’re committed to making them the best they can be. We’re going deeper on browser rendering for agents, because there will be a long tail of services that don’t yet speak MCP, and agents will still need to interact with them. These aren’t stopgaps — they’re part of a complete platform.
But we’re also building what comes next: the isolates, the protocols, and the identity models that agents actually need. Our job is to make sure you don’t have to choose between what works today and what’s right for tomorrow.
Security in the model, not around it
If agents are going to handle our professional and personal tasks — reading our email, operating on our code, interacting with our financial services — then security has to be built into the execution model, not layered on after the fact.
CISOs have been the first to confront this. The productivity gains from putting agents in everyone’s hands are real, but today, most agent deployments are fraught with risk: prompt injection, data exfiltration, unauthorized API access, opaque tool usage.
A developer’s vibe-coding agent needs access to repositories and deployment pipelines. An enterprise’s customer service agent needs access to internal APIs and user data. In both cases, securing the environment today means stitching together credentials, network policies, and access controls that were never designed for autonomous software.
Cloudflare has been building two platforms in parallel: our developer platform, for people who build applications, and our zero trust platform, for organizations that need to secure access. For a while, these served distinct audiences.
But “how do I build this agent?” and “how do I make sure it’s safe?” are increasingly the same question. We’re bringing these platforms together so that all of this is native to how agents run, not a separate layer you bolt on.
Agents that follow the rules
There’s another dimension to the agent era that goes beyond compute and security: economics and governance.
When agents interact with the Internet on our behalf — reading articles, consuming APIs, accessing services — there needs to be a way for the people and organizations who create that content and run those services to set terms and get paid. Today, the web’s economic model is built around human attention: ads, paywalls, subscriptions.
Agents don’t have attention (well, not that kind of attention). They don’t see ads. They don’t click through cookie banners.
If we want an Internet where agents can operate freely and where publishers, content creators, and service providers are fairly compensated, we need new infrastructure for it. We’re building tools that make it easy for publishers and content owners to set and enforce policies for how agents interact with their content.
Building a better Internet has always meant making sure it works for everyone — not just the people building the technology, but the people whose work and creativity make the Internet worth using. That doesn’t change in the age of agents. It becomes more important.
The platform for developers and agents
Our vision for the developer platform has always been to provide a comprehensive platform that just works: from experiment, to MVP, to scaling to millions of users. But providing the primitives is only part of the equation. A great platform also has to think about how everything works together, and how it integrates into your development flow.
That job is evolving. It used to be purely about developer experience, making it easy for humans to build, test, and ship. Increasingly, it’s also about helping agents help humans, and making the platform work not just for the people building agents, but for the agents themselves. Can an agent find the latest most up-to- date best practices? How easily can it discover and invoke the tools and CLIs it needs? How seamlessly can it move from writing code to deploying it?
This week, we’re shipping improvements across both dimensions — making Cloudflare better for the humans building on it and for the agents running on it.
Building for the future is a team sport
Building for the future is not something we can do alone. Every major Internet transition from HTTP/1.1 to HTTP/2 and HTTP/3, from TLS 1.2 to 1.3 — has required the industry to converge on shared standards. The shift to agents will be no different.
Cloudflare has a long history of contributing to and helping push forward the standards that make the Internet work. We’ve been deeply involved in the IETF for over a decade, helping develop and deploy protocols like QUIC, TLS 1.3, and Encrypted Client Hello. We were a founding member of WinterTC, the ECMA technical committee for JavaScript runtime interoperability. We open-sourced the Workers runtime itself, because we believe the foundation should be open.
We’re bringing the same approach to the agentic era. We’re excited to be part of the Linux Foundation and AAIF, and to help support and push forward standards like MCP that will be foundational for the agentic future. Since Anthropic introduced MCP, we’ve worked closely with them to build the infrastructure for remote MCP servers, open-sourced our own implementations, and invested in making the protocol practical at scale.
Last year, alongside Coinbase, we co-founded the x402 Foundation, an open, neutral standard that revives the long-dormant HTTP 402 status code to give agents a native way to pay for the services and content they consume.
Agent identity, authorization, payment, safety: these all need open standards that no single company can define alone.
Stay tuned
This week, we’re making announcements across every dimension of the agent stack: compute, connectivity, security, identity, economics, and developer experience.
The Internet wasn’t built for AI. The cloud wasn’t built for agents. But Cloudflare has always been about helping build a better Internet — and what “better” means changes with each era. This is the era of agents. This week, follow along and we’ll show you what we’re building for it.
Cloudflare’s network recently passed a major milestone: we crossed 500 terabits per second (Tbps) of external capacity.
When we say 500 Tbps, we mean total provisioned external interconnection capacity: the sum of every port facing a transit provider, private peering partner, Internet exchange, or Cloudflare Network Interconnect (CNI) port across all 330+ cities. This is not peak traffic. On any given day, our peak utilization is a fraction of that number. (The rest is our DDoS budget.)
It’s a long way from where we started. In 2010, we launched from a small office above a nail salon in Palo Alto, with a single transit provider and a reverse proxy you could set up by changing two nameservers.
The early days of transit and peering
Our first transit provider was nLayer Communications, a network most people now know as GTT. nLayer gave us our first capacity and our first hands-on company experience in peering relationships and the careful balance between cost and performance.
From there, we grew city by city: Chicago, Ashburn, San Jose, Amsterdam, Tokyo. Each new data center meant negotiating colocation contracts, pulling fiber, racking servers, and establishing peering through Internet exchanges. The Internet isn’t actually a cloud, of course. It is a collection of specific rooms full of cables, and we spent years learning the nuances of every one of them.
Not every city was a straightforward deployment, having to deal with missing hardware, customs strikes, and even dental floss. In a single month in 2018, we opened up in 31 cities in 24 days: from Kathmandu and Baghdad to Reykjavík and Chișinău. When we opened our 127th data center in Macau, we were protecting 7 million Internet properties. Today, with data centers in 330+ cities, we protect more than 20% of the web.
When the network became the security layer
As our footprint grew, customers asked for more than just website caching. They needed to protect employees, replace aging Multiprotocol Label Switching (MPLS) circuits, and secure entire enterprise networks. Instead of traditional appliances, we built systems to establish secure tunnels to private subnets and advertise enterprise IP space directly from our global network via BGP.
The scale of threats grew in parallel. In 2025, we mitigated a 31.4 Tbps DDoS attack lasting 35 seconds. The source was the Aisuru-Kimwolf botnet, including many infected Android TVs. It was one of over 5,000 attacks we blocked that day. No engineer was paged.
A decade ago, an attack of that magnitude would have required nation-state resources to counter. Today, our network handles it in seconds without human intervention. That is what operating at a 500 Tbps scale requires: moving the intelligence to every server in our network so the network can defend itself.
How our network responds to an attack
Here is what actually happens when an attack hits our network. Packets arrive at the network interface card (NIC) and immediately enter an eXpress Data Path (XDP) program chain managed by xdpd, running in driver mode. Among the first programs in that chain is l4drop, which evaluates each packet against mitigation rules in extended Berkeley Packet Filter (eBPF). Those rules are generated by dosd, our denial of service daemon, which runs on every server in our fleet. Each dosd instance samples incoming traffic, builds a table of the heaviest hitters it sees, and broadcasts that table to every other instance in the colo. The result is a shared colo-wide view of traffic, and because every server works from the same data, they reach the same mitigation decision.
When dosd detects an attack pattern, the resulting rule is applied locally via l4drop and propagates globally via Quicksilver, our distributed key-value (KV) store, reaching every server in every data center within seconds. Only after surviving l4drop do packets reach Unimog, our Layer 4 (L4) load balancer, which distributes them across healthy servers in the data center. For Magic Transit customers routing enterprise network traffic through our edge, flowtrackd adds a further layer of stateful TCP inspection, tracking connection state and dropping packets that don’t belong to legitimate flows.
The 31.4 Tbps attack we mitigated followed exactly this path. No traffic was backhauled to a centralized scrubbing center. No human intervened. Every server in the targeted data centers independently recognized the attack and began dropping malicious packets at line rate, before those packets consumed a single CPU cycle of application processing. The software is only half the story: none of it works if the ports aren’t there to absorb the traffic in the first place.
A distributed developer platform
Running code on every server in our network was a natural consequence of controlling the full stack. If we already ran eBPF programs on every machine to drop attack traffic, we could run customer application code there too. That insight became Workers, and later KV and Durable Objects.
Our developer platform runs in every city we operate in, not in a handful of cloud regions. In 2025, we added Containers to Workers, so heavier workloads can run at the edge too. V8 isolates and custom filesystem layers minimize cold starts. Your code runs where your users are, on the same servers that drop attack traffic at line rate via l4drop. Attack traffic is dropped before it reaches the network stack. Your application never sees it.
Forward-looking protocols: IPv6, RPKI, ASPA
We were early adopters of IPv6 and Resource Public Key Infrastructure (RPKI). BGP hijacks cause real outages and security breaches. RPKI allows us to drop invalid routes from peers, ensuring traffic goes where it is supposed to. We sign Route Origin Authorizations (ROAs) for our prefixes and enforce Route Origin Validation on ingress. We reject RPKI-invalid routes, even when that occasionally breaks reachability to networks with misconfigured ROAs.
Autonomous System Provider Authorization (ASPA) is next. RPKI validates who owns a prefix. ASPA validates the path it took to get here. RPKI is a passport check at the destination, confirming the right owner, while ASPA is a flight manifest check: it verifies every network the traffic passed through. A route leak is like a passenger who boarded in the wrong city; RPKI would not catch it, but ASPA will.
Current ecosystem adoption for ASPA looks like RPKI did in 2015. We were one of the first networks to deploy RPKI at scale, and today, 867,000 prefixes in the global routing table have valid RPKI certificates, up from near zero a decade ago. At our scale, the protocols we choose have real consequences for the broader Internet. We push for adoption early because waiting means more hijacks and more leaks in the meantime.
AI agents and the evolving Internet
AI has changed what it means to have a presence on the web. For most of the Internet’s history, traffic was human-generated, by people clicking links in browsers. Today, AI crawlers, model training pipelines, and autonomous agents now account for more than 4% of all HTML requests across our network, comparable to Googlebot itself. “User action” crawling, where an AI visits a page because a human asked it a question, grew over 15x in 2025 alone.
AI crawlers behave differently than browsers at the infrastructure level. Browsers load a page and stop. Crawlers instead fetch every linked resource at maximum throughput with no pause between requests. At our scale, distinguishing legitimate AI crawling from actual attacks is a real engineering problem. Our detection systems use a combination of verified bot IP ranges, TLS fingerprinting, behavioral analysis, and robots.txt compliance signals to make that distinction, and to give site owners the data they need to decide which crawlers to allow.
At the TLS layer, for example, a legitimate browser presents a ClientHello with a predictable set of cipher suites, extensions, and ordering that matches its declared User-Agent. A crawler spoofing that User-Agent but using a stripped-down TLS library will present a different fingerprint, and that mismatch is one of the signals our systems use to classify the request before it reaches the origin.
Help us build the next 500 Tbps
What started above a nail salon in Palo Alto is now a 500 Tbps network in 330+ cities across 125+ countries, where every server runs our developer platform and security services, not just cache. That is sixteen years of architectural decisions compounding, and we owe it to the 13,000+ networks and partners who peer with us. We are not done.
If you are a network operator, peer with us. Our peering policy and interconnection details are on PeeringDB. If you are interested in embedding Cloudflare infrastructure directly within your network, reach out to our team at [email protected], to join the Edge Partner Program.
AI is rapidly changing how software is written, deployed, and used. Trends point to a future where AIs can write custom software quickly and easily: “instant software.” Taken to an extreme, it might become easier for a user to have an AI write an application on demand—a spreadsheet, for example—and delete it when you’re done using it than to buy one commercially. Future systems could include a mix: both traditional long-term software and ephemeral instant software that is constantly being written, deployed, modified, and deleted.
AI is changing cybersecurity as well. In particular, AI systems are getting better at finding and patching vulnerabilities in code. This has implications for both attackers and defenders, depending on the ways this and related technologies improve.
In this essay, I want to take an optimistic view of AI’s progress, and to speculate what AI-dominated cybersecurity in an age of instant software might look like. There are a number of unknowns that will factor into how the arms race between attacker and defender might play out.
How flaw discovery might work
On the attacker side, the ability of AIs to automatically find and exploit vulnerabilities has increased dramatically over the past few months. We are already seeing both government and criminal hackers using AI to attack systems. The exploitation part is critical here, because it gives an unsophisticated attacker capabilities far beyond their understanding. As AIs get better, expect more attackers to automate their attacks using AI. And as individuals and organizations can increasingly run powerful AI models locally, AI companies monitoring and disrupting malicious AI use will become increasingly irrelevant.
Expect open-source software, including open-source libraries incorporated in proprietary software, to be the most targeted, because vulnerabilities are easier to find in source code. Unknown No. 1 is how well AI vulnerability discovery tools will work against closed-source commercial software packages. I believe they will soon be good enough to find vulnerabilities just by analyzing a copy of a shipped product, without access to the source code. If that’s true, commercial software will be vulnerable as well.
Particularly vulnerable will be software in IoT devices: things like internet-connected cars, refrigerators, and security cameras. Also industrial IoT software in our internet-connected power grid, oil refineries and pipelines, chemical plants, and so on. IoT software tends to be of much lower quality, and industrial IoT software tends to be legacy.
Instant software is differently vulnerable. It’s not mass market. It’s created for a particular person, organization, or network. The attacker generally won’t have access to any code to analyze, which makes it less likely to be exploited by external attackers. If it’s ephemeral, any vulnerabilities will have a short lifetime. But lots of instant software will live on networks for a long time. And if it gets uploaded to shared tool libraries, attackers will be able to download and analyze that code.
All of this points to a future where AIs will become powerful tools of cyberattack, able to automatically find and exploit vulnerabilities in systems worldwide.
Automating patch creation
But that’s just half of the arms race. Defenders get to use AI, too. These same AI vulnerability-finding technologies are even more valuable for defense. When the defensive side finds an exploitable vulnerability, it can patch the code and deny it to attackers forever.
How this works in practice depends on another related capability: the ability of AIs to patch vulnerable software, which is closely related to their ability to write secure code in the first place.
AIs are not very good at this today; the instant software that AIs create is generally filled with vulnerabilities, both because AIs write insecure code and because the people vibe coding don’t understand security. OpenClaw is a good example of this.
Unknown No. 2 is how much better AIs will get at writing secure code. The fact that they’re trained on massive corpuses of poorly written and insecure code is a handicap, but they are getting better. If they can reliably write vulnerability-free code, it would be an enormous advantage for the defender. And AI-based vulnerability-finding makes it easier for an AI to train on writing secure code.
We can envision a future where AI tools that find and patch vulnerabilities are part of the typical software development process. We can’t say that the code would be vulnerability-free—that’s an impossible goal—but it could be without any easily findable vulnerabilities. If the technology got really good, the code could become essentially vulnerability-free.
Patching lags and legacy software
For new software—both commercial and instant—this future favors the defender. For commercial and conventional open-source software, it’s not that simple. Right now, the world is filled with legacy software. Much of it—like IoT device software—has no dedicated security team to update it. Sometimes it is incapable of being patched. Just as it’s harder for AIs to find vulnerabilities when they don’t have access to the source code, it’s harder for AIs to patch software when they are not embedded in the development process.
I’m not as confident that AI systems will be able to patch vulnerabilities as easily as they can find them, because patching often requires more holistic testing and understanding. That’s Unknown No. 3: how quickly AIs will be able to create reliable software updates for the vulnerabilities they find, and how quickly customers can update their systems.
Today, there is a time lag between when a vendor issues a patch and customers install that update. That time lag is even longer for large organizational software; the risk of an update breaking the underlying software system is just too great for organizations to roll out updates without testing them first. But if AI can help speed up that process, by writing patches faster and more reliably, and by testing them in some AI-generated twin environment, the advantage goes to the defender. If not, the attacker will still have a window to attack systems until a vulnerability is patched.
Toward self-healing
In a truly optimistic future, we can imagine a self-healing network. AI agents continuously scan the ever-evolving corpus of commercial and custom AI-generated software for vulnerabilities, and automatically patch them on discovery.
For that to work, software license agreements will need to change. Right now, software vendors control the cadence of security patches. Giving software purchasers this ability has implications about compatibility, the right to repair, and liability. Any solutions here are the realm of policy, not tech.
If the defense can find, but can’t reliably patch, flaws in legacy software, that’s where attackers will focus their efforts. If that’s the case, we can imagine a continuously evolving AI-powered intrusion detection, continuously scanning inputs and blocking malicious attacks before they get to vulnerable software. Not as transformative as automatically patching vulnerabilities in running code, but nevertheless valuable.
The power of these defensive AI systems increases if they are able to coordinate with each other, and share vulnerabilities and updates. A discovery by one AI can quickly spread to everyone using the affected software. Again: Advantage defender.
There are other variables to consider. The relative success of attackers and defenders also depends on how plentiful vulnerabilities are, how easy they are to find, whether AIs will be able to find the more subtle and obscure vulnerabilities, and how much coordination there is among different attackers. All this comprises Unknown No. 4.
Vulnerability economics
Presumably, AIs will clean up the obvious stuff first, which means that any remaining vulnerabilities will be subtle. Finding them will take AI computing resources. In the optimistic scenario, defenders pool resources through information sharing, effectively amortizing the cost of defense. If information sharing doesn’t work for some reason, defense becomes much more expensive, as individual defenders will need to do their own research. But instant software means much more diversity in code: an advantage to the defender.
This needs to be balanced with the relative cost of attackers finding vulnerabilities. Attackers already have an inherent way to amortize the costs of finding a new vulnerability and create a new exploit. They can vulnerability hunt cross-platform, cross-vendor, and cross-system, and can use what they find to attack multiple targets simultaneously. Fixing a common vulnerability often requires cooperation among all the relevant platforms, vendors, and systems. Again, instant software is an advantage to the defender.
But those hard-to-find vulnerabilities become more valuable. Attackers will attempt to do what the major intelligence agencies do today: find “nobody but us” zero-day exploits. They will either use them slowly and sparingly to minimize detection or quickly and broadly to maximize profit before they’re patched. Meanwhile, defenders will be both vulnerability hunting and intrusion detecting, with the goal of patching vulnerabilities before the attackers find them.
We can even imagine a market for vulnerability sharing, where the defender who finds a vulnerability and creates a patch is compensated by everyone else in the information-sharing/repair network. This might be a stretch, but maybe.
Up the stack
Even in the most optimistic future, attackers aren’t going to just give up. They will attack the non-software parts of the system, such as the users. Or they’re going to look for loopholes in the system: things that the system technically allows but were unintended and unanticipated by the designers—whether human or AI—and can be used by attackers to their advantage.
What’s left in this world are attacks that don’t depend on finding and exploiting software vulnerabilities, like social engineering and credential stealing attacks. And we have already seen how AI-generated deepfakes make social engineering easier. But here, too, we can imagine defensive AI agents that monitor users’ behaviors, watching for signs of attack. This is another AI use case, and one that I’m not even sure how to think about in terms of the attacker/defender arms race. But at least we’re pushing attacks up the stack.
Also, attackers will attempt to infiltrate and influence defensive AIs and the networks they use to communicate, poisoning their output and degrading their capabilities. AI systems are vulnerable to all sorts of manipulations, such as prompt injection, and it’s unclear whether we will ever be able to solve that. This is Unknown No. 5, and it’s a biggie. There might always be a “trusting trust problem.”
No future is guaranteed. We truly don’t know whether these technologies will continue to improve and when they will plateau. But given the pace at which AI software development has improved in just the past few months, we need to start thinking about how cybersecurity works in this instant software world.
EDITED TO ADD: Twoessays published after I wrote this. Both are good illustrations of where we are re AI vulnerability discovery. Things are changing very fast.
WebinarTV searches the internet for public Zoom invites, joins the meetings, secretly records them, and publishes (alternate link) the recordings. It doesn’t use the Zoom record feature, so Zoom can’t do anything about it.
Client-side skimming attacks have a boring superpower: they can steal data without breaking anything. The page still loads. Checkout still completes. All it needs is just one malicious script tag.
If that sounds abstract, here are two recent examples of such skimming attacks:
In January 2026, Sansec reported a browser-side keylogger running on an employee merchandise store for a major U.S. bank, harvesting personal data, login credentials, and credit card information.
In September 2025, attackers published malicious releases of widely used npm packages. If those packages were bundled into front-end code, end users could be exposed to crypto-stealing in the browser.
To further our goal of building a better Internet, Cloudflare established a core tenet during our Birthday Week 2025: powerful security features should be accessible without requiring a sales engagement. In pursuit of this objective, we are announcing two key changes today:
First, Cloudflare Client-Side Security Advanced (formerly Page Shield add-on) is now available to self-serve customers. And second, domain-based threat intelligence is now complimentary for all customers on the free Client-Side Security bundle.
In this post, we’ll explain how this product works and highlight a new AI detection system designed to identify malicious JavaScript while minimizing false alarms. We’ll also discuss several real-world applications for these tools.
How Cloudflare Client-Side Security works
Cloudflare Client-Side Security assesses 3.5 billion scripts per day, protecting 2,200 scripts per enterprise zone on average.
Under the hood, Client-Side Security collects these signals using browser reporting (for example, Content Security Policy), which means you don’t need scanners or app instrumentation to get started, and there is zero latency impact to your web applications. The only prerequisite is that your traffic is proxied through Cloudflare.
Client-Side Security Advanced provides immediate access to powerful security features:
Smarter malicious script detection: Using in-house machine learning, this capability is now enhanced with assessments from a Large Language Model (LLM). Read more details below.
Code change monitoring: Continuous code change detection and monitoring is included, which is essential for meeting compliance likePCI DSS v4, requirement 11.6.1.
Proactive blocking rules: Benefit from positive content security rules that are maintained and enforced through continuous monitoring.
Detecting malicious intent JavaScripts
Managing client-side security is a massive data problem. For an average enterprise zone, our systems observe approximately 2,200 unique scripts; smaller business zones frequently handle around 1,000. This volume alone is difficult to manage, but the real challenge is the volatility of the code.
Roughly a third of these scripts undergo code updates within any 30-day window. If a security team attempted to manually approve every new DOM (document object model) interaction or outbound connection, the resulting overhead would paralyze the development pipeline.
Instead, our detection strategy focuses on what a script is trying to do. That includes intent classification work we’ve written about previously. In short, we analyze the script’s behavior using an Abstract Syntax Tree (AST). By breaking the code down into its logical structure, we can identify patterns that signal malicious intent, regardless of how the code is obfuscated.
The high cost of false positives
Client-side security operates differently than active vulnerability scanners deployed across the web, where a Web Application Firewall (WAF) would constantly observe matched attack signatures. While a WAF constantly blocks high-volume automated attacks, a client-side compromise (such as a breach of an origin server or a third-party vendor) is a rare, high-impact event. In an enterprise environment with rigorous vendor reviews and code scanning, these attacks are rare.
This rarity creates a problem. Because real attacks are infrequent, a security system’s detections are statistically more likely to be false positives. For a security team, these false alarms create fatigue and hide real threats. To solve this, we integrated a Large Language Model (LLM) into our detection pipeline, drastically reducing the false positive rate.
Adding an LLM-based second opinion for triage
Our frontline detection engine is a Graph Neural Network (GNN). GNNs are particularly well-suited for this task: they operate on the Abstract Syntax Tree (AST) of the JavaScript code, learning structural representations that capture execution patterns regardless of variable renaming, minification, or obfuscation. In machine learning terms, the GNN learns an embedding of the code’s graph structure that generalizes across syntactic variations of the same semantic behavior.
The GNN is tuned for high recall. We want to catch novel, zero-day threats. Its precision is already remarkably high: less than 0.3% of total analyzed traffic is flagged as a false positive (FP). However, at Cloudflare’s scale of 3.5 billion scripts assessed daily, even a sub-0.3% FP rate translates to a volume of false alarms that can be disruptive to customers.
The core issue is a classic class imbalance problem. While we can collect extensive malicious samples, the sheer diversity of benign JavaScript across the web is practically infinite. Heavily obfuscated but perfectly legitimate scripts — like bot challenges, tracking pixels, ad-tech bundles, and minified framework builds — can exhibit structural patterns that overlap with malicious code in the GNN’s learned feature space. As much as we try to cover a huge variety of interesting benign cases, the model simply has not seen enough of this infinite variety during training.
This is precisely where Large Language Models (LLMs) complement the GNN. LLMs possess a deep semantic understanding of real-world JavaScript practices: they recognize domain-specific idioms, common framework patterns, and can distinguish sketchy-but-innocuous obfuscation from genuinely malicious intent.
Rather than replacing the GNN, we designed a cascading classifier architecture:
Every script is first evaluated by the GNN. If the GNN predicts the script as benign, the detection pipeline terminates immediately. This incurs only the minimal latency of the GNN for the vast majority of traffic, completely bypassing the heavier computation time of the LLM.
If the GNN flags the script as potentially malicious (above the decision threshold), the script is forwarded to an open-source LLM hosted on Cloudflare Workers AI for a second opinion.
The LLM, provided with a security-specialized prompt context, semantically evaluates the script’s intent. If it determines the script is benign, it overrides the GNN’s verdict.
This two-stage design gives us the best of both worlds: the GNN’s high recall for structural malicious patterns, combined with the LLM’s broad semantic understanding to filter out false positives.
As we previously explained, our GNN is trained on publicly accessible script URLs, the same scripts any browser would fetch. The LLM inference at runtime runs entirely within Cloudflare’s network via Workers AI using open-source models (we currently use gpt-oss-120b).
As an additional safety net, every script flagged by the GNN is logged to Cloudflare R2 for posterior analysis. This allows us to continuously audit whether the LLM’s overrides are correct and catch any edge cases where a true attack might have been inadvertently filtered out. Yes, we dogfood our own storage products for our own ML pipeline.
The results from our internal evaluations on real production traffic are compelling. Focusing on total analyzed traffic under the JS Integrity threat category, the secondary LLM validation layer reduced false positives by nearly 3x: dropping the already low ~0.3% FP rate down to ~0.1%. When evaluating unique scripts, the impact is even more dramatic: the FP rate plummets a whopping ~200x, from ~1.39% down to just 0.007%.
At our scale, cutting the overall false positive rate by two-thirds translates to millions fewer false alarms for our customers every single day. Crucially, our True Positive (actual attack) detection capability includes a fallback mechanism:as noted above, we audit the LLM’s overrides to check for possible true attacks that were filtered by the LLM.
Because the LLM acts as a highly reliable precision filter in this pipeline, we can now afford to lower the GNN’s decision threshold, making it even more aggressive. This means we catch novel, highly obfuscated True Attacks that would have previously fallen just below the detection boundary, all without overwhelming customers with false alarms. In the next phase, we plan to push this even further.
Catching zero-days in the wild: The core.js router exploit
This two-stage architecture is already proving its worth in the wild. Just recently, our detection pipeline flagged a novel, highly obfuscated malicious script (core.js) targeting users in specific regions.
In this case, the payload was engineered to commandeer home routers (specifically Xiaomi OpenWrt-based devices). Upon closer inspection via deobfuscation, the script demonstrated significant situational awareness: it queries the router’s WAN configuration (dynamically adapting its payload using parameters like wanType=dhcp, wanType=static, and wanType=pppoe), overwrites the DNS settings to hijack traffic through Chinese public DNS servers, and even attempts to lock out the legitimate owner by silently changing the admin password. Instead of compromising a website directly, it had been injected into users’ sessions via compromised browser extensions.
To evade detection, the script’s core logic was heavily minified and packed using an array string obfuscator — a classic trick, but effective enough that traditional threat intelligence platforms like VirusTotal have not yet reported detections at the time of this writing.
Our GNN successfully revealed the underlying malicious structure despite the obfuscation, and the Workers AI LLM confidently confirmed the intent. Here is a glimpse of the payload showing the target router API and the attempt to inject a rogue DNS server:
This is exactly the kind of sophisticated, zero-day threat that a static signature-based WAF would miss but our structural and semantic AI approach catches.
Today we are making domain-based threat intelligence available to all Cloudflare Client-Side Security customers, regardless of whether you use the Advanced offering.
In 2025, we saw many non-enterprise customers affected by client-side attacks, particularly those customers running webshops on the Magento platform. These attacks persisted for days or even weeks after they were publicized. Small and medium-sized companies often lack the enterprise-level resources and expertise needed to maintain a high security standard.
By providing domain-based threat intelligence to everyone, we give site owners a critical, direct signal of attacks affecting their users. This information allows them to take immediate action to clean up their site and investigate potential origin compromises.
To begin, simply enable Client-Side Security with a toggle in the dashboard. We will then highlight any JavaScript or connections associated with a known malicious domain.
Get started with Client-Side Security Advanced for PCI DSS v4
To learn more about Client-Side Security Advanced pricing, please visit the plans page. Before committing, we will estimate the cost based on your last month’s HTTP requests, so you know exactly what to expect.
Client-Side Security Advanced has all the tools you need to meet the requirements of PCI DSS v4 as an e-commerce merchant, particularly 6.4.3 and 11.6.1. Sign up today in the dashboard.
In December, the Trump administration signed an executive order that neutered states’ ability to regulate AI by ordering his administration to both sue and withhold funds from states that try to do so. This action pointedly supported industry lobbyists keen to avoid any constraints and consequences on their deployment of AI, while undermining the efforts of consumers, advocates, and industry associations concerned about AI’s harms who have spent years pushing for state regulation.
Trump’s actions have clarified the ideological alignments around AI within America’s electoral factions. They set down lines on a new playing field for the midterm elections, prompting members of his party, the opposition, and all of us to consider where we stand in the debate over how and where to let AI transform our lives.
In a May 2025 survey of likely voters nationwide, more than 70% favored state and federal regulators having a hand in AI policy. A December 2025 poll by Navigator Research found similar results, with a massive net +48% favorability for more AI regulation. Yet despite the overwhelming preference of both voters and his party’s elected leaders—Congress was essentially unanimous in defeating a previous state AI regulation moratorium—Trump has delivered on a key priority of the industry. The order explicitly challenges the will of voters across blue and red states, from California to South Dakota, scrambling political positions around the technology and setting up a new ideological battleground in the upcoming race for Congress.
There are a number of ways that candidates and parties may try to capitalize on this emerging wedge issue before the midterms.
In 2025, much of the popular debate around AI was cast in terms of humans versus machines. Advances in AI and the companies it is associated with, it is said, come at the expense of humans. A new model release with greater capabilities for writing, teaching, or coding means more people in those disciplines losing their jobs.
This is a humanist debate. Making us talk to an AI customer-support agent is an affront to our dignity. Using AI to help generate media sacrifices authenticity. AI chatbots that persuade and manipulate assault our liberty. There is philosophical merit to these arguments, and yet they seem to have limited political salience.
Populism versus institutionalism is a better way to frame this debate in the context of US politics. The MAGA movement is widely understood to be a realignment of American party politics to ally the Republican party with populism, and the Democratic party with defenders of traditional institutions of American government and their democratic norms.
This frame is shattered by Trump’s AI order, which unabashedly serves economic elites at the expense of populist consumer protections. It is part of an ongoing courting process between MAGA and big tech, where the Trump political project sacrifices the interests of consumers and its populist credentials as it cozies up to tech moguls.
We are starting to see populist resistance to this government/big tech alignment emerge on the local scale. People in Maryland, Arizona, North Carolina, Michigan and many other states are vigorously opposing AI datacenters in their communities, based on environmental and energy-affordability impacts. These centers of opposition are politically diverse; both progressives and Trump-supporting voters are turning out in force, influencing their local elected officials to resist datacenter development.
This opposition to the physical infrastructure of corporate AI is so far staying local, but it may yet translate into a national and politically aligned movement that could divide the MAGA coalition.
Any policy discussions about AI should include the individual harms associated with job loss, as employers seek to replace laborers with machines. It should also include the systemic economic risks associated with concentrated and supercharged AI investment, the democratic risks associated with the increased power in monopolistic and politically influential tech companies, and the degradation of civic functions like journalism and education by AI. In order for our free market to function in the public interest, the companies amassing wealth and profiting from AI must be forced to take ownership of, and internalize, these costs.
The political salience of AI will grow to meet the staggering scale of financial investment and societal impact it is already commanding. There is an opportunity for enterprising candidates, of either political party, to take the mantle of opposing AI-linked harms in the midterm elections.
Political solutions start with organizing, and broadening the base of political engagement around these issues beyond the locally salient topic of datacenters. Movement leaders and elected officials in states that have taken action on AI regulation should mobilize around the blatant industry capture, wealth extraction, and corporate favoritism reflected in the Trump executive order. AI is no longer just a policy issue for governments to discuss: it is a political issue that voters must decide on and demand accountability on.
Today Intel is expanding their Arc B-series video card lineup in a big way, with the launch of a pair of new Arc Pro graphics cards: the Arc Pro B70 and the Arc Pro B65. Joining Intel’s existing Arc Pro B-series video cards, the latest cards out of Intel are also the company’s most powerful […]
But if an agent (or an MCP server) is going to execute code generated on-the-fly by AI to perform tasks, that code needs to run somewhere, and that somewhere needs to be secure. You can’t just eval() AI-generated code directly in your app: a malicious user could trivially prompt the AI to inject vulnerabilities.
You need a sandbox: a place to execute code that is isolated from your application and from the rest of the world, except for the specific capabilities the code is meant to access.
Sandboxing is a hot topic in the AI industry. For this task, most people are reaching for containers. Using a Linux-based container, you can start up any sort of code execution environment you want. Cloudflare even offers our container runtime and our Sandbox SDK for this purpose.
But containers are expensive and slow to start, taking hundreds of milliseconds to boot and hundreds of megabytes of memory to run. You probably need to keep them warm to avoid delays, and you may be tempted to reuse existing containers for multiple tasks, compromising the security.
If we want to support consumer-scale agents, where every end user has an agent (or many!) and every agent writes code, containers are not enough. We need something lighter.
And we have it.
Dynamic Worker Loader: a lean sandbox
Tucked into our Code Mode post in September was the announcement of a new, experimental feature: the Dynamic Worker Loader API. This API allows a Cloudflare Worker to instantiate a new Worker, in its own sandbox, with code specified at runtime, all on the fly.
Dynamic Worker Loader is now in open beta, available to all paid Workers users.
// Have your LLM generate code like this.
let agentCode: string = `
  export default {
    async myAgent(param, env, ctx) {
      // ...
    }
  }
`;

// Get RPC stubs representing APIs the agent should be able
// to access. (This can be any Workers RPC API you define.)
let chatRoomRpcStub = ...;

// Load a worker to run the code, using the worker loader
// binding.
let worker = env.LOADER.load({
  // Specify the code.
  compatibilityDate: "2026-03-01",
  mainModule: "agent.js",
  modules: { "agent.js": agentCode },

  // Give agent access to the chat room API.
  env: { CHAT_ROOM: chatRoomRpcStub },

  // Block internet access. (You can also intercept it.)
  globalOutbound: null,
});

// Call RPC methods exported by the agent code.
await worker.getEntrypoint().myAgent(param);
That’s it.
100x faster
Dynamic Workers use the same underlying sandboxing mechanism that the entire Cloudflare Workers platform has been built on since its launch, eight years ago: isolates. An isolate is an instance of the V8 JavaScript execution engine, the same engine used by Google Chrome. They are how Workers work.
An isolate takes a few milliseconds to start and uses a few megabytes of memory. That’s around 100x faster and 10x-100x more memory efficient than a typical container.
That means that if you want to start a new isolate for every user request, on-demand, to run one snippet of code, then throw it away, you can.
Unlimited scalability
Many container-based sandbox providers impose limits on global concurrent sandboxes and rate of sandbox creation. Dynamic Worker Loader has no such limits. It doesn’t need to, because it is simply an API to the same technology that has powered our platform all along, which has always allowed Workers to seamlessly scale to millions of requests per second.
Want to handle a million requests per second, where every single request loads a separate Dynamic Worker sandbox, all running concurrently? No problem!
Zero latency
One-off Dynamic Workers usually run on the same machine — the same thread, even — as the Worker that created them. No need to communicate around the world to find a warm sandbox. Isolates are so lightweight that we can just run them wherever the request landed. Dynamic Workers are supported in every one of Cloudflare’s hundreds of locations around the world.
It’s all JavaScript
The only catch, vs. containers, is that your agent needs to write JavaScript.
Technically, Workers (including dynamic ones) can use Python and WebAssembly, but for small snippets of code — like that written on-demand by an agent — JavaScript will load and run much faster.
We humans tend to have strong preferences on programming languages, and while many love JavaScript, others might prefer Python, Rust, or countless others.
But we aren’t talking about humans here. We’re talking about AI. AI will write any language you want it to. LLMs are experts in every major language. Their training data in JavaScript is immense.
JavaScript, by its nature on the web, is designed to be sandboxed. It is the correct language for the job.
Tools defined in TypeScript
If we want our agent to be able to do anything useful, it needs to talk to external APIs. How do we tell it about the APIs it has access to?
MCP defines schemas for flat tool calls, but not programming APIs. OpenAPI offers a way to express REST APIs, but it is verbose, both in the schema itself and the code you’d have to write to call it.
For APIs exposed to JavaScript, there is a single, obvious answer: TypeScript.
Agents know TypeScript. TypeScript is designed to be concise. With very few tokens, you can give your agent a precise understanding of your API.
// Interface to interact with a chat room.
interface ChatRoom {
  // Get the last `limit` messages of the chat log.
  getHistory(limit: number): Promise<Message[]>;

  // Subscribe to new messages. Dispose the returned object
  // to unsubscribe.
  subscribe(callback: (msg: Message) => void): Promise<Disposable>;

  // Post a message to chat.
  post(text: string): Promise<void>;
}

type Message = {
  author: string;
  time: Date;
  text: string;
}
Compare this with the equivalent OpenAPI spec (which is so long you have to scroll to see it all):
openapi: 3.1.0
info:
  title: ChatRoom API
  description: >
    Interface to interact with a chat room.
  version: 1.0.0

paths:
  /messages:
    get:
      operationId: getHistory
      summary: Get recent chat history
      description: Returns the last `limit` messages from the chat log, newest first.
      parameters:
        - name: limit
          in: query
          required: true
          schema:
            type: integer
            minimum: 1
      responses:
        "200":
          description: A list of messages.
          content:
            application/json:
              schema:
                type: array
                items:
                  $ref: "#/components/schemas/Message"

    post:
      operationId: postMessage
      summary: Post a message to the chat room
      requestBody:
        required: true
        content:
          application/json:
            schema:
              type: object
              required:
                - text
              properties:
                text:
                  type: string
      responses:
        "204":
          description: Message posted successfully.

  /messages/stream:
    get:
      operationId: subscribeMessages
      summary: Subscribe to new messages via SSE
      description: >
        Opens a Server-Sent Events stream. Each event carries a JSON-encoded
        Message object. The client unsubscribes by closing the connection.
      responses:
        "200":
          description: An SSE stream of new messages.
          content:
            text/event-stream:
              schema:
                description: >
                  Each SSE `data` field contains a JSON-encoded Message object.
                $ref: "#/components/schemas/Message"

components:
  schemas:
    Message:
      type: object
      required:
        - author
        - time
        - text
      properties:
        author:
          type: string
        time:
          type: string
          format: date-time
        text:
          type: string
We think the TypeScript API is better. It’s fewer tokens and much easier to understand (for both agents and humans).
Dynamic Worker Loader makes it easy to implement a TypeScript API like this in your own Worker and then pass it in to the Dynamic Worker either as a method parameter or in the env object. The Workers Runtime will automatically set up a Cap’n Web RPC bridge between the sandbox and your harness code, so that the agent can invoke your API across the security boundary without ever realizing that it isn’t using a local library.
That means your agent can write code like this:
// Thinking: The user asked me to summarize recent chat messages from Alice.
// I will filter the recent message history in code so that I only have to
// read the relevant messages.
let history = await env.CHAT_ROOM.getHistory(1000);
return history.filter(msg => msg.author == "alice");
HTTP filtering and credential injection
If you prefer to give your agents HTTP APIs, that’s fully supported. Using the globalOutbound option to the worker loader API, you can register a callback to be invoked on every HTTP request, in which you can inspect the request, rewrite it, inject auth keys, respond to it directly, block it, or anything else you might like.
For example, you can use this to implement credential injection (token injection): When the agent makes an HTTP request to a service that requires authorization, you add credentials to the request on the way out. This way, the agent itself never knows the secret credentials, and therefore cannot leak them.
Using a plain HTTP interface may be desirable when an agent is talking to a well-known API that is in its training set, or when you want your agent to use a library that is built on a REST API (the library can run inside the agent’s sandbox).
With that said, in the absence of a compatibility requirement, TypeScript RPC interfaces are better than HTTP:
As shown above, a TypeScript interface requires far fewer tokens to describe than an HTTP interface.
The agent can write code to call TypeScript interfaces using far fewer tokens than equivalent HTTP.
With TypeScript interfaces, since you are defining your own wrapper interface anyway, it is easier to narrow the interface to expose exactly the capabilities that you want to provide to your agent, both for simplicity and security. With HTTP, you are more likely implementing filtering of requests made against some existing API. This is hard, because your proxy must fully interpret the meaning of every API call in order to properly decide whether to allow it, and HTTP requests are complicated, with many headers and other parameters that could all be meaningful. It ends up being easier to just write a TypeScript wrapper that only implements the functions you want to allow.
Battle-hardened security
Hardening an isolate-based sandbox is tricky, as it is a more complicated attack surface than hardware virtual machines. Although all sandboxing mechanisms have bugs, security bugs in V8 are more common than security bugs in typical hypervisors. When using isolates to sandbox possibly-malicious code, it’s important to have additional layers of defense-in-depth. Google Chrome, for example, implemented strict process isolation for this reason, but it is not the only possible solution.
We have nearly a decade of experience securing our isolate-based platform. Our systems automatically deploy V8 security patches to production within hours — faster than Chrome itself. Our security architecture features a custom second-layer sandbox with dynamic cordoning of tenants based on risk assessments. We’ve extended the V8 sandbox itself to leverage hardware features like MPK. We’ve teamed up with (and hired) leading researchers to develop novel defenses against Spectre. We also have systems that scan code for malicious patterns and automatically block them or apply additional layers of sandboxing. And much more.
When you use Dynamic Workers on Cloudflare, you get all of this automatically.
Helper libraries
We’ve built a number of libraries that you might find useful when working with Dynamic Workers:
Code Mode
@cloudflare/codemode simplifies running model-generated code against AI tools using Dynamic Workers. At its core is DynamicWorkerExecutor(), which constructs a purpose-built sandbox with code normalisation to handle common formatting errors, and direct access to a globalOutbound fetcher for controlling fetch() behaviour inside the sandbox — set it to null for full isolation, or pass a Fetcher binding to route, intercept or enrich outbound requests from the sandbox.
The Code Mode SDK also provides two server-side utility functions. codeMcpServer({ server, executor }) wraps an existing MCP Server, replacing its tool surface with a single code() tool. openApiMcpServer({ spec, executor, request }) goes further: given an OpenAPI spec and an executor, it builds a complete MCP Server with search() and execute() tools as used by the Cloudflare MCP Server, and better suited to larger APIs.
In both cases, the code generated by the model runs inside Dynamic Workers, with calls to external services made over RPC bindings passed to the executor.
Dynamic Workers expect pre-bundled modules. @cloudflare/worker-bundler handles that for you: give it source files and a package.json, and it resolves npm dependencies from the registry, bundles everything with esbuild, and returns the module map the Worker Loader expects.
It also supports full-stack apps via createApp — bundle a server Worker, client-side JavaScript, and static assets together, with built-in asset serving that handles content types, ETags, and SPA routing.
@cloudflare/shell gives your agent a virtual filesystem inside a Dynamic Worker. Agent code calls typed methods on a state object — read, write, search, replace, diff, glob, JSON query/update, archive — with structured inputs and outputs instead of string parsing.
Storage is backed by a durable Workspace (SQLite + R2), so files persist across executions. Coarse operations like searchFiles, replaceInFiles, and planEdits minimize RPC round-trips — the agent issues one call instead of looping over individual files. Batch writes are transactional by default: if any write fails, earlier writes roll back automatically.
import { Workspace } from "@cloudflare/shell";
import { stateTools } from "@cloudflare/shell/workers";
import { DynamicWorkerExecutor, resolveProvider } from "@cloudflare/codemode";

const workspace = new Workspace({
  sql: this.ctx.storage.sql, // Works with any DO's SqlStorage, D1, or custom SQL backend
  r2: this.env.MY_BUCKET, // large files spill to R2 automatically
  name: () => this.name   // lazy — resolved when needed, not at construction
});

// Code runs in an isolated Worker sandbox with no network access
const executor = new DynamicWorkerExecutor({ loader: env.LOADER });

// The LLM writes this code; `state.*` calls dispatch back to the host via RPC
const result = await executor.execute(
  `async () => {
    // Search across all TypeScript files for a pattern
    const hits = await state.searchFiles("src/**/*.ts", "answer");
    // Plan multiple edits as a single transaction
    const plan = await state.planEdits([
      { kind: "replace", path: "/src/app.ts",
        search: "42", replacement: "43" },
      { kind: "writeJson", path: "/src/config.json",
        value: { version: 2 } }
    ]);
    // Apply atomically — rolls back on failure
    return await state.applyEditPlan(plan);
  }`,
  [resolveProvider(stateTools(workspace))]
);
The package also ships prebuilt TypeScript type declarations and a system prompt template, so you can drop the full state API into your LLM context in a handful of tokens.
Developers want their agents to write and execute code against tool APIs, rather than making sequential tool calls one at a time. With Dynamic Workers, the LLM generates a single TypeScript function that chains multiple API calls together, runs it in a Dynamic Worker, and returns the final result back to the agent. As a result, only the output, and not every intermediate step, ends up in the context window. This cuts both latency and token usage, and produces better results, especially when the tool surface is large.
Our own Cloudflare MCP server is built exactly this way: it exposes the entire Cloudflare API through just two tools — search and execute — in under 1,000 tokens, because the agent writes code against a typed API instead of navigating hundreds of individual tool definitions.
Building custom automations
Developers are using Dynamic Workers to let agents build custom automations on the fly. Zite, for example, is building an app platform where users interact through a chat interface — the LLM writes TypeScript behind the scenes to build CRUD apps, connect to services like Stripe, Airtable, and Google Calendar, and run backend logic, all without the user ever seeing a line of code. Every automation runs in its own Dynamic Worker, with access to only the specific services and libraries that the endpoint needs.
“To enable server-side code for Zite’s LLM-generated apps, we needed an execution layer that was instant, isolated, and secure. Cloudflare’s Dynamic Workers hit the mark on all three, and out-performed all of the other platforms we benchmarked for speed and library support. The NodeJS compatible runtime supported all of Zite’s workflows, allowing hundreds of third party integrations, without sacrificing on startup time. Zite now services millions of execution requests daily thanks to Dynamic Workers.”
— Antony Toron, CTO and Co-Founder, Zite
Running AI-generated applications
Developers are building platforms that generate full applications from AI — either for their customers or for internal teams building prototypes. With Dynamic Workers, each app can be spun up on demand, then put back into cold storage until it’s invoked again. Fast startup times make it easy to preview changes during active development. Platforms can also block or intercept any network requests the generated code makes, keeping AI-generated apps safe to run.
Pricing
Dynamically-loaded Workers are priced at $0.002 per unique Worker loaded per day (as of this post’s publication), in addition to the usual CPU time and invocation pricing of regular Workers.
For AI-generated “code mode” use cases, where every Worker is a unique one-off, this means the price is $0.002 per Worker loaded (plus CPU and invocations). This cost is typically negligible compared to the inference costs to generate the code.
During the beta period, the $0.002 charge is waived. As pricing is subject to change, please always check our Dynamic Workers pricing for the most current information.
Get Started
If you’re on the Workers Paid plan, you can start using Dynamic Workers today.
Dynamic Workers Starter
Use this “hello world” starter to get a Worker deployed that can load and execute Dynamic Workers.
Dynamic Workers Playground
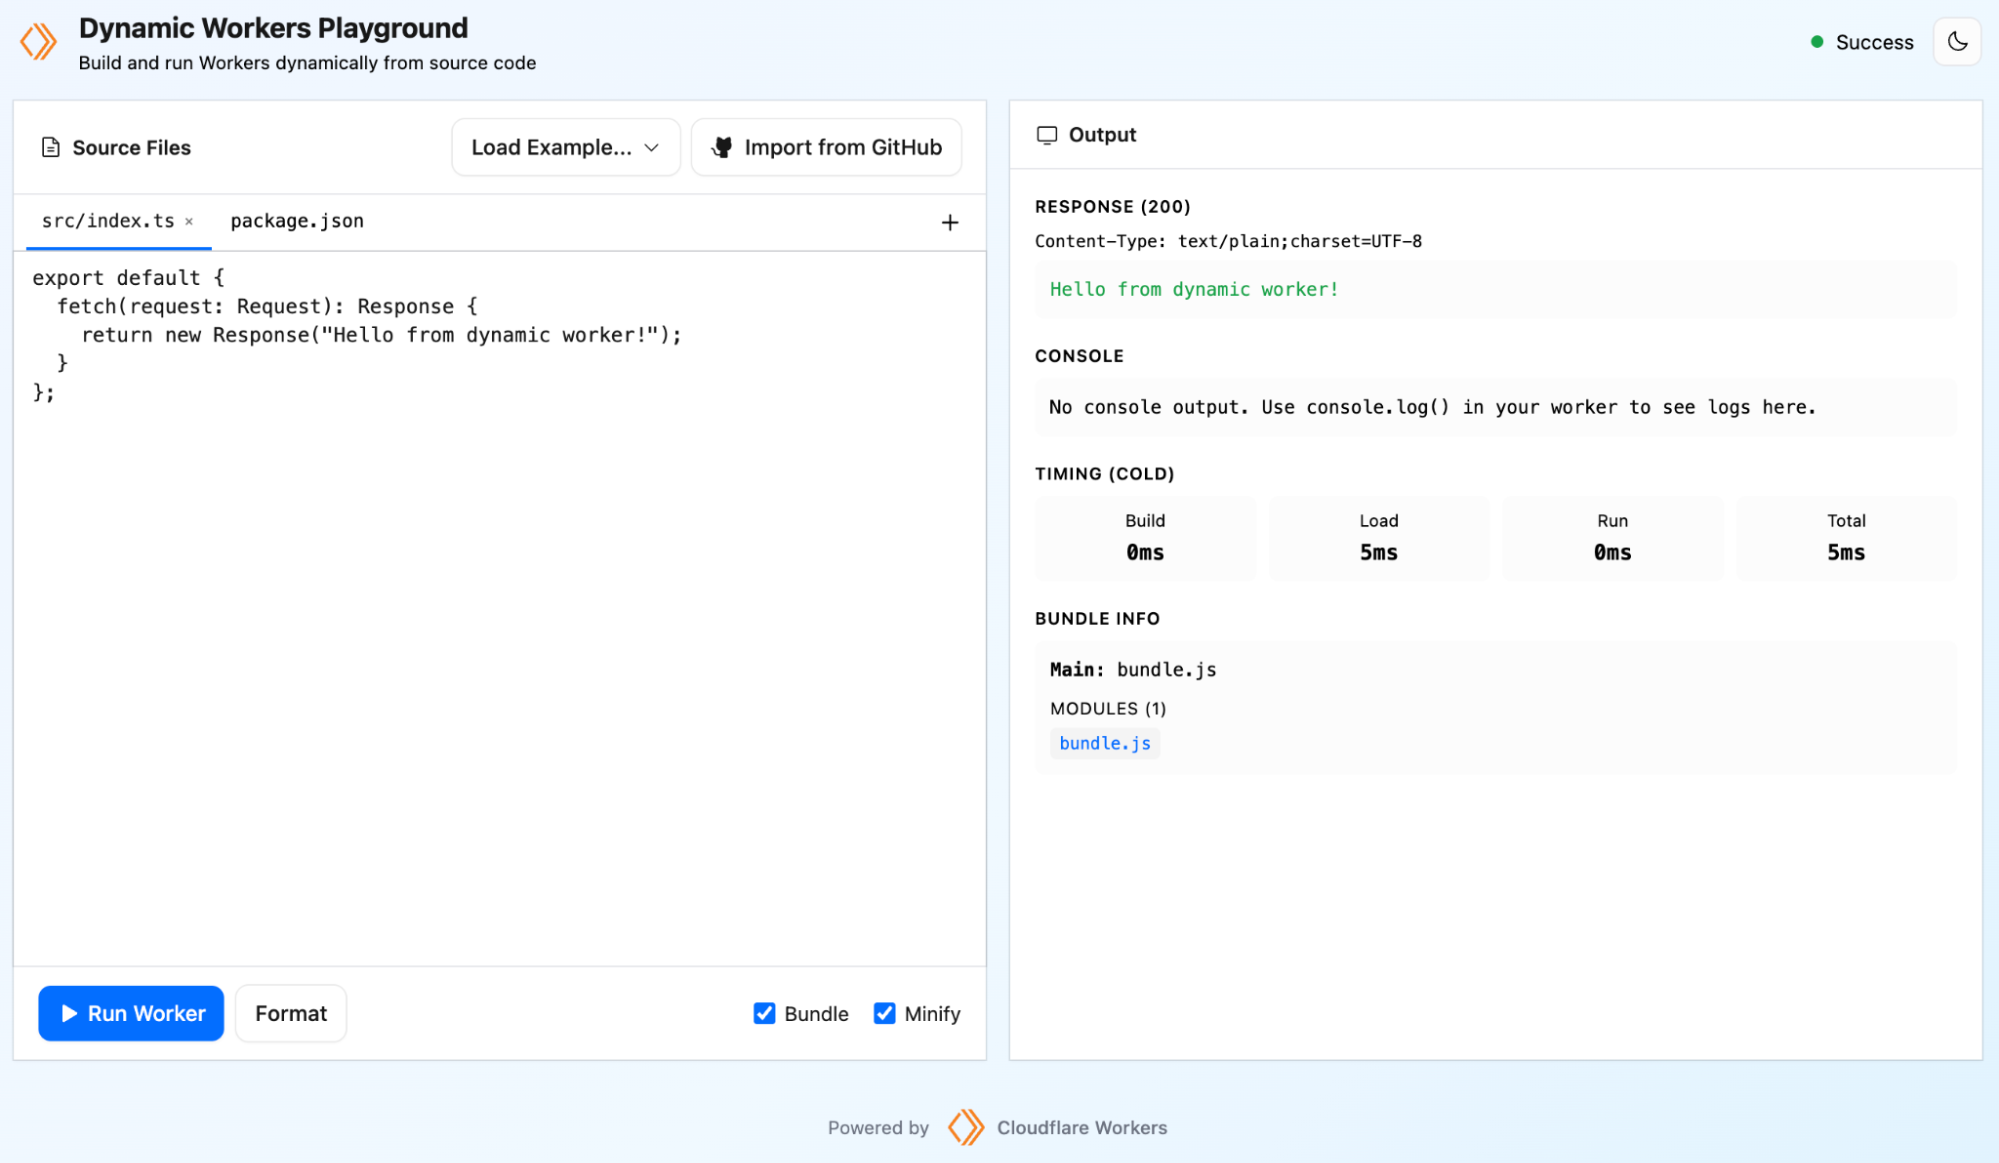
You can also deploy the Dynamic Workers Playground, where you’ll be able to write or import code, bundle it at runtime with @cloudflare/worker-bundler, execute it through a Dynamic Worker, see real-time responses and execution logs.
Dynamic Workers are fast, scalable, and lightweight. Find us on Discord if you have any questions. We’d love to see what you build!
Japan’s election last month and the rise of the country’s newest and most innovative political party, Team Mirai, illustrates the viability of a different way to do politics.
In this model, technology is used to make democratic processes stronger, instead of undermining them. It is harnessed to root out corruption, instead of serving as a cash cow for campaign donations.
Imagine an election where every voter has the opportunity to opine directly to politicians on precisely the issues they care about. They’re not expected to spend hours becoming policy experts. Instead, an AI Interviewer walks them through the subject, answering their questions, interrogating their experience, even challenging their thinking.
Voters get immediate feedback on how their individual point of view matches—or doesn’t—a party’s platform, and they can see whether and how the party adopts their feedback. This isn’t like an opinion poll that politicians use for calculating short-term electoral tactics. It’s a deliberative reasoning process that scales, engaging voters in defining policy and helping candidates to listen deeply to their constituents.
This is happening today in Japan. Constituents have spent about eight thousand hours engaging with Mirai’s AI Interviewer since 2025. The party’s gamified volunteer mobilization app, Action Board, captured about 100,000 organizer actions per day in the runup to last week’s election.
It’s how Team Mirai, which translates to ‘The Future Party,’ does politics. Its founder, Takahiro Anno, first ran for local office in 2024 as a 33 year old software engineer standing for Governor of Tokyo. He came in fifth out of 56 candidates, winning more than 150,000 votes as an unaffiliated political outsider. He won attention by taking a distinctive stance on the role of technology in democracy and using AI aggressively in voter engagement.
Last year, Anno ran again, this time for the Upper Chamber of the national legislature—the Diet—and won. Now the head of a new national party, Anno found himself with a platform for making his vision of a new way of doing politics a reality.
In this recent House of Representatives election, Team Mirai shot up to win nearly four million votes. In the lower chamber’s proportional representation system, that was good enough for eleven total seats—the party’s first ever representation in the Japanese House—and nearly three times what it achieved in last year’s Upper Chamber election.
Anno’s party stood for election without aligning itself on the traditional axes of left and right. Instead, Team Mirai, heavily associated with young, urban voters, sought to unite across the ideological spectrum by taking a radical position on a different axis: the status quo and the future. Anno told us that Team Mirai believes it can triple its representation in the Diet after the next elections in each chamber, an ostentatious goal that seems achievable given their rapid rise over the past year.
In the American context, the idea of a small party unifying voters across left and right sounds like a pipe dream. But there is evidence it worked in Japan. Team Mirai won an impressive 11% of proportional representation votes from unaffiliated voters, nearly twice the share of the larger electorate. The centerpiece of the party’s policy platform is not about the traditional hot button issues, it’s about democracy itself, and how it can be enhanced by embracing a futuristic vision of digital democracy.
Anno told us how his party arrived at its manifesto for this month’s elections, and why it looked different from other parties’ in important ways. Team Mirai collected more than 38,000 online questions and more than 6,000 discrete policy suggestions from voters using its AI Policy app, which is advertised as a ‘manifesto that speaks for itself.’
After factoring in all this feedback, Team Mirai maintained a contrarian position on the biggest issue of the election: the sales tax and affordability. Rather than running on a reduction of the national sales tax like the major parties, Team Mirai reviewed dozens of suggestions from the public and ultimately proposed to keep that tax level while providing support to families through a child tax credit and lowering the required contribution for social insurance. Anno described this as another future-facing strategy: less price relief in the short term, but sustained funding for essential programs.
Anno has always intended to build a different kind of party. After receiving roughly $1 million in public funding apportioned to Team Mirai based on its single seat in the Upper Chamber last year, Anno began hiring engineers to enhance his software tools for digital democracy.
Anno described Team Mirai to us as a ‘utility party;’ basic infrastructure for Japanese democracy that serves the broader polity rather than one faction. Their Gikai (‘assembly’) app illustrates the point. It provides a portal for constituents to research bills, using AI to generate summaries, to describe their impacts, to surfacing media reporting on the issue, and to answer users’ questions. Like all their software, it’s open source and free for anyone, in any party, to use.
After last week’s victory, Team Mirai now has about $5 million in public funding and ambitions to grow the influence of their digital democracy platform. Anno told us Team Mirai has secured an agreement with the LDP, Japan’s dominant ruling party, to begin using Team Mirai’s Gikai and corruption-fighting Mirumae financial transparency tool.
AI is the issue driving the most societal and economic change we will encounter in our lifetime, yet US political parties are largely silent. But AI and Big Tech companies and their owners are ramping up their political spending to influence the parties. To the extent that AI has shown up in our politics, it seems to be limited to the question of where to site the next generation of data centers and how to channel populist backlash to big tech.
Those are causes worthy of political organizing, but very few US politicians are leveraging the technology for public listening or other pro-democratic purposes. With the midterms still nine months away and with innovators like Team Mirai making products in the open for anyone to use, there is still plenty of time for an American politician to demonstrate what a new politics could look like.
This essay was written with Nathan E. Sanders, and originally appeared in Tech Policy Press.
We’re making Cloudflare the best place for building and deploying agents. But reliable agents aren’t built on prompts alone; they require a robust, coordinated infrastructure of underlying primitives.
At Cloudflare, we have been building these primitives for years: Durable Objects for state persistence, Workflows for long running tasks, and Dynamic Workers or Sandbox containers for secure execution. Powerful abstractions like the Agents SDK are designed to help you build agents on top of Cloudflare’s Developer Platform.
But these primitives only provided the execution environment. The agent still needed a model capable of powering it.
Starting today, Workers AI is officially in the big models game. We now offer frontier open-source models on our AI inference platform. We’re starting by releasing Moonshot AI’s Kimi K2.5 model on Workers AI. With a full 256k context window and support for multi-turn tool calling, vision inputs, and structured outputs, the Kimi K2.5 model is excellent for all kinds of agentic tasks. By bringing a frontier-scale model directly into the Cloudflare Developer Platform, we’re making it possible to run the entire agent lifecycle on a single, unified platform.
The heart of an agent is the AI model that powers it, and that model needs to be smart, with high reasoning capabilities and a large context window. Workers AI now runs those models.
The price-performance sweet spot
We spent the last few weeks testing Kimi K2.5 as the engine for our internal development tools. Within our OpenCode environment, Cloudflare engineers use Kimi as a daily driver for agentic coding tasks. We have also integrated the model into our automated code review pipeline; you can see this in action via our public code review agent, Bonk, on Cloudflare GitHub repos. In production, the model has proven to be a fast, efficient alternative to larger proprietary models without sacrificing quality.
Serving Kimi K2.5 began as an experiment, but it quickly became critical after reviewing how the model performs and how cost-efficient it is. As an illustrative example: we have an agent that does security reviews of Cloudflare’s codebases. This agent processes over 7B tokens per day, and using Kimi, it has caught more than 15 confirmed issues in a single codebase. Doing some rough math, if we had run this agent on a mid-tier proprietary model, we would have spent $2.4M a year for this single use case, on a single codebase. Running this agent with Kimi K2.5 cost just a fraction of that: we cut costs by 77% simply by making the switch to Workers AI.
As AI adoption increases, we are seeing a fundamental shift not only in how engineering teams are operating, but how individuals are operating. It is becoming increasingly common for people to have a personal agent like OpenClaw running 24/7. The volume of inference is skyrocketing.
This new rise in personal and coding agents means that cost is no longer a secondary concern; it is the primary blocker to scaling. When every employee has multiple agents processing hundreds of thousands of tokens per hour, the math for proprietary models stops working. Enterprises will look to transition to open-source models that offer frontier-level reasoning without the proprietary price tag. Workers AI is here to facilitate this shift, providing everything from serverless endpoints for a personal agent to dedicated instances powering autonomous agents across an entire organization.
The large model inference stack
Workers AI has served models, including LLMs, since its launch two years ago, but we’ve historically prioritized smaller models. Part of the reason was that for some time, open-source LLMs fell far behind the models from frontier model labs. This changed with models like Kimi K2.5, but to serve this type of very large LLM, we had to make changes to our inference stack. We wanted to share with you some of what goes on behind the scenes to support a model like Kimi.
We’ve been working on custom kernels for Kimi K2.5 to optimize how we serve the model, which is built on top of our proprietary Infire inference engine. Custom kernels improve the model’s performance and GPU utilization, unlocking gains that would otherwise go unclaimed if you were just running the model out of the box. There are also multiple techniques and hardware configurations that can be leveraged to serve a large model. Developers typically use a combination of data, tensor, and expert parallelization techniques to optimize model performance. Strategies like disaggregated prefill are also important, in which you separate the prefill and generation stages onto different machines in order to get better throughput or higher GPU utilization. Implementing these techniques and incorporating them into the inference stack takes a lot of dedicated experience to get right.
Workers AI has already done the experimentation with serving techniques to yield excellent throughput on Kimi K2.5. A lot of this does not come out of the box when you self-host an open-source model. The benefit of using a platform like Workers AI is that you don’t need to be a Machine Learning Engineer, a DevOps expert, or a Site Reliability Engineer to do the optimizations required to host it: we’ve already done the hard part, you just need to call an API.
Beyond the model — platform improvements for agentic workloads
In concert with this launch, we’ve also improved our platform and are releasing several new features to help you build better agents.
Prefix caching and surfacing cached tokens
When you work with agents, you are likely sending a large number of input tokens as part of the context: this could be detailed system prompts, tool definitions, MCP server tools, or entire codebases. Inputs can be as large as the model context window, so in theory, you could be sending requests with almost 256k input tokens. That’s a lot of tokens.
When an LLM processes a request, the request is broken down into two stages: the prefill stage processes input tokens and the output stage generates output tokens. These stages are usually sequential, where input tokens have to be fully processed before you can generate output tokens. This means that sometimes the GPU is not fully utilized while the model is doing prefill.
With multi-turn conversations, when you send a new prompt, the client sends all the previous prompts, tools, and context from the session to the model as well. The delta between consecutive requests is usually just a few new lines of input; all the other context has already gone through the prefill stage during a previous request. This is where prefix caching helps. Instead of doing prefill on the entire request, we can cache the input tensors from a previous request, and only do prefill on the new input tokens. This saves a lot of time and compute from the prefill stage, which means a faster Time to First Token (TTFT) and a higher Tokens Per Second (TPS) throughput as you’re not blocked on prefill.
Workers AI has always done prefix caching, but we are now surfacing cached tokens as a usage metric and offering a discount on cached tokens compared to input tokens. (Pricing can be found on the model page.) We also have new techniques for you to leverage in order to get a higher prefix cache hit rate, reducing your costs.
New session affinity header for higher cache hit rates
In order to route to the same model instance and take advantage of prefix caching, we use a new x-session-affinity header. When you send this header, you’ll improve your cache hit ratio, leading to more cached tokens and subsequently, faster TTFT, TPS, and lower inference costs.
You can pass the new header like below, with a unique string per session or per agent. Some clients like OpenCode implement this automatically out of the box. Our Agents SDK starter has already set up the wiring to do this for you, too.
curl -X POST \
"https://api.cloudflare.com/client/v4/accounts/{ACCOUNT_ID}/ai/run/@cf/moonshotai/kimi-k2.5" \
  -H "Authorization: Bearer {API_TOKEN}" \
  -H "Content-Type: application/json" \
  -H "x-session-affinity: ses_12345678" \
  -d '{
    "messages": [
      {
        "role": "system",
        "content": "You are a helpful assistant."
      },
      {
        "role": "user",
        "content": "What is prefix caching and why does it matter?"
      }
    ],
    "max_tokens": 2400,
    "stream": true
  }'
Redesigned async APIs
Serverless inference is really hard. With a pay-per-token business model, it’s cheaper on a single request basis because you don’t need to pay for entire GPUs to service your requests. But there’s a trade-off: you have to contend with other people’s traffic and capacity constraints, and there’s no strict guarantee that your request will be processed. This is not unique to Workers AI — it’s evidently the case across serverless model providers, given the frequent news reports of overloaded providers and service disruptions. While we always strive to serve your request and have built-in autoscaling and rebalancing, there are hard limitations (like hardware) that make this a challenge.
For volumes of requests that would exceed synchronous rate limits, you can submit batches of inferences to be completed asynchronously. We’re introducing a revamped Asynchronous API, which means that for asynchronous use cases, you won’t run into Out of Capacity errors and inference will execute durably at some point. Our async API looks more like flex processing than a batch API, where we process requests in the async queue as long as we have headroom in our model instances. With internal testing, our async requests usually execute within 5 minutes, but this will depend on what live traffic looks like. As we bring Kimi to the public, we will tune our scaling accordingly, but the async API is the best way to make sure you don’t run into capacity errors in durable workflows. This is perfect for use cases that are not real-time, such as code scanning agents or research agents.
Workers AI previously had an asynchronous API, but we’ve recently revamped the systems under the hood. We now rely on a pull-based system versus the historical push-based system, allowing us to pull in queued requests as soon as we have capacity. We’ve also added better controls to tune the throughput of async requests, monitoring GPU utilization in real-time and pulling in async requests when utilization is low, so that critical synchronous requests get priority while still processing asynchronous requests efficiently.
To use the asynchronous API, you would send your requests as seen below. We also have a way to set up event notifications so that you can know when the inference is complete instead of polling for the request.
// (1.) Push a request in queue
// pass queueRequest: true
let res = await env.AI.run("@cf/moonshotai/kimi-k2.5", {
  "requests": [{
    "messages": [{
      "role": "user",
      "content": "Tell me a joke"
    }]
  }, {
    "messages": [{
      "role": "user",
      "content": "Explain the Pythagoras theorem"
    }]
  }, ...{<add more requests in a batch>} ];
}, {
  queueRequest: true,
});


// (2.) grab the request id
let request_id;
if(res && res.request_id){
  request_id = res.request_id;
}
// (3.) poll the status
let res = await env.AI.run("@cf/moonshotai/kimi-k2.5", {
  request_id: request_id
});

if(res && res.status === "queued" || res.status === "running") {
 // retry by polling again
 ...
}
else
 return Response.json(res); // This will contain the final completed response
Grab’s Analytics Data Warehouse (ADW) team supports over 1,000 users each month and manages an extensive repository of more than 15,000 tables, which powers approximately 50% of all queries within our data lake.
However, the manual process of addressing “quick questions” is time-consuming and labor-intensive, thus creating a bottleneck in our operations.
The team was drowning in repetitive requests, spending approximately 40% of their time or an equivalent of roughly 2 days every week, on tasks like:
Answering the same questions about data definitions
Tracing data sources and troubleshooting
Running quality checks to verify data integrity
Basic enhancement requests
We deployed a multi-agent AI system that autonomously answers simpler questions and collaboratively addresses more complex requests. This led us to reclaim significant engineering bandwidth and unlock hundreds of hours of productivity monthly.
Solution
Tech stack
FastAPI and LangGraph: We use FastAPI to handle requests and LangGraph to manage the complex state and cyclical logic required for multi-agent collaboration. Unlike simple Large Language Model (LLM) calls, LangGraph allows our agents to loop back, ask for more information, or hand off tasks to one another.
Redis & PostgreSQL: Redis handles our caching and real-time session needs, while PostgreSQL serves as the persistent memory, storing conversation history and agent metadata.
Figure 1. Architecture tech stack.
Hubble: A centralized metadata management platform and data catalog, built on open-source DataHub.
Genchi: A data quality observability platform that enforces data contracts.
Lighthouse: A platform that tracks execution status and monitors pipeline health.
From request to resolution
The journey begins in Slack. When a user submits a request, it is categorized into one of two streams:
Enhancement requests: These are routed to the Enhancement Agent, which interacts directly with our core engineering tools like GitLab, Apache Spark, and Airflow to propose and test code changes.
General questions: These are funneled through our investigation pathway. The system orchestrates a “huddle” between the Data Agent (querying Trino, Hive, or Delta Lake), the Code Search Agent (analyzing GitLab), and the On-call Agent (checking Confluence and Slack for ongoing incidents).
By decoupling the “brain” (the LLM) from the “hands” (the specialized agents and tools), we created a system that is both capable and easy to debug.
Why specialized agents beat a single “Super AI”
We could have built one massive AI trained to handle every question, but specialized agents are easier to build, maintain, and improve than a monolithic system.
The table below illustrates the comparison between a single AI system and a multi-agent system:
Approach
Advantages
Challenges
Single AI (Monolithic)
One model to maintain, single inference call
Hard to debug, changes affect everything, generalist performance
We chose the multi-agent approach because maintainability and accuracy mattered more than shaving off a few seconds of latency. When you’re replacing a multi-hour manual investigation, taking a few minutes for a precise answer is a massive leap in operational throughput.
The architecture: Two pathways, five specialized agents
When a question arrives through Slack, the system first determines which pathway to take:
Figure 2. Agent workflows, using a Classifier that controls communication flow and task delegation.
Enhancement pathway: Semi-Automated code changes
For requests like “Can you add a new column for customer_segment?” or “We need to change the aggregation logic for revenue”, the Enhancement Agent handles the heavy lifting.
Enhancement Agent receives user requirements and proposes code changes:
Generates code changes and creates a merge request (MR).
Runs changes in a test environment.
Flags governance concerns (Personally Identifiable Information (PII) classification, Service Level Agreements (SLAs), backward compatibility).
The workflow:
User creates a JIRA request.
Agent analyzes requirements and gathers context through interactive dialogue with the engineer.
Agent creates an MR with suggested code.
Engineer reviews the MR.
If valid, agent runs changes in test environment.
Engineer reviews results against test cases.
If tests pass, engineer merges the MR.
Why is the workflow semi-automated by design? Code changes to production pipelines require human judgment. The agent accelerates the process by doing the research, writing the code, and running tests, but humans make the final approval.
Investigation pathway: Four agents working together
For questions like “Why does this data look wrong?” or “Where does this metric come from?”, the system uses a coordinated team of specialists.
The Classifier is the first responder for investigation questions. It:
Parses the question to extract key information (tables, scripts, specific data requests).
Determines which specialist agents are needed and in what sequence.
Provides reasoning and task descriptions for each recommended agent.
Example: For the question “Why does this ID look wrong?”, the Classifier routes the question to: Data Agent → Code Search Agent → On-call Agent (if needed).
Data Agent performs the data investigation:
Enhances the prompt’s context with the table and column metadata.
Executes queries with guardrails (PII detection, command validation).
Validates schemas to avoid unnecessary scans and hallucinations.
Retrieves sample data with LLM exploratory comments.
Example: It queries vehicle_id from the table to validate the user’s observation against the actual data.
Code Search Agent analyzes the code:
Traces column transformations through the codebase.
Follows table lineage through multiple transformation steps.
Generates plain-language explanations of transformation logic.
Highlights divergences from documentation or stakeholder expectations.
Example: It can trace a vehicle_id column from the final table back through 5 transformation steps to the original source, explaining each change along the way.
On-call Agent monitors production systems and assists with urgent issues:
Searches Slack channels for announcements about outages, source table failures, and delays.
Checks observability platforms for pipeline health, logs, and retry policies.
Validates data quality metrics (null counts, duplicates, range validation).
Produces incident notes and initial Root Cause Analysis (RCA) when issues are identified.
Example: If the Data Agent detects SLA breaches or missing partitions, it may consult the On-call Agent for production context.
Summarizer Agent refines responses from the previous agents:
Handles conflicting information.
Combines responses into a coherent narrative.
Makes the answer concise and structured.
Ensures consistency across agent findings.
Generating the summary is the final step before human review.
Seeing the system in action
The best way to understand how this multi-agent system works is to see it handle real scenarios. Let’s walk through two common situations our team faces daily.
Scenario 1: Adding a new column
The request: A stakeholder raises a JIRA ticket requesting, “Please add a customer_segment column to the rides table. Source data is available in the user_profiles table.”
In the traditional workflow, a data engineer would spend a significant portion of their afternoon clarifying requirements, developing and testing code, similar to the workflow steps in “Figure 2: Agent workflows”.
With the Enhancement Agent, the entire process is completed autonomously in minutes. The agent performs these tasks in sequence:
Read the JIRA ticket: Agent fetches the ticket details to understand the exact requirements: what column needs to be added, which table is involved, and where the source data comes from.
Discover the relevant code: Using intelligent search capabilities, it locates the specific pipeline files in our codebase that need modification. It navigates through the repository structure to find the right transformation scripts.
Run validation checks: Before making any changes, it validates:
The requested column exists in the upstream source table.
The column doesn’t already exist in the target table.
Schema compatibility and data quality requirements are met.
Generate database schema changes: The agent references existing Data Definition Language (DDL) scripts to understand the standard format, then automatically generates the necessary schema modification scripts. These scripts are added to the MR alongside the code changes.
Create the MR: All changes, including code modifications and schema scripts, are packaged into an MR with proper documentation, making it ready for review.
Enable pipeline execution: Once the MR is validated, users can interact with the bot to trigger the data pipeline and start testing their changes on Airflow. They can optionally specify date ranges or other parameters to control the test runs.
The entire process, from ticket to deployable MR, completes autonomously in minutes, with full traceability at every step.
Figure 3. Enhancement Agent workflow.
Scenario 2: Investigating faulty-looking data
The question: “Why is the ID in the vehicles table unreadable?”
Traditionally, the data engineer typically performs these steps:
Search through various data catalogs to locate relevant information.
Manually track the data’s origin and transformation path.
Validate SQL queries.
Examine logs.
This is how it looks with agents:
Step 1: Classifier analyzes the question
Parses the question: determines all three specialist agents are needed.
Plans the sequence: Data Agent → Code Search Agent → On-call Agent
Provides reasoning: “Need to verify data format, trace transformation logic, and check for production incidents”.
Step 2: Data Agent investigates
Retrieves metadata, which helps in building a SQL query for exploring samples.
Queries actual data. The result confirms the user’s observation with the actual sample and identifies that IDs appear in Universally Unique Identifier (UUID) format, and they’re “unreadable”.
Searches Grab’s data catalog to find dimension tables that can help decipher UUID in a more human-readable format.
Finds an appropriate dimension table and builds a join query to test readability.
Conclusion from Data Agent: “The ID column contains UUID format values. These can be joined with dim_vehicles table to get human-readable vehicle names. The format is consistent and valid—not corrupted data.”
Figure 4. Data Agent response.
Step 3: Code Search Agent traces lineage
Scans the transformation and lineage logic in the codebase to see exactly how the ID is extracted. It discovers that the ID is a raw UUID from a JSON payload directly from the source system.
Queries the source table for samples directly. The “unreadable” text pattern matches the data in the vehicles table, confirming that it is not a bug introduced by Spark transformations.
Conclusion from Code Search Agent: “The ‘unreadable’ UUID format comes directly from the source system. No transformation is applied. This is not a bug introduced by our Spark pipelines—it’s the native format from the upstream system”.
Figure 5. Code Search Agent response.
Step 4: On-call Agent checks production health
Checks Airflow pipeline status.
Searches Slack channels for incidents.
Checks data quality metrics.
Conclusion from On-call Agent: “No production incidents detected. Pipeline running successfully. Data quality metrics are within normal ranges. No recent complaints or issues reported in communication channels.”
Figure 6. On-call Agent response.
Step 5: Summarizer Agent synthesizes the answer
User concern: ID values appear “unreadable”.
Data Agent finding: IDs are valid UUIDs, can be joined with dim_vehicles for readable names.
Code Search finding: UUID format comes directly from source system, not a transformation bug.
On-call finding: No production issues, pipeline healthy, data quality normal.
Provides a structured answer to: “Why is the ID in the vehicles table unreadable?”
Figure 7. Summarizer Agent response.
Step 6: Human review and delivery
The answer is posted on Slack, and a data engineer can review the response and approve it.
The initial response time has been reduced to just a few minutes, in contrast to the previous hours-long manual search.
Step 7: Continue conversation
After an answer is posted, anyone can engage in a continued conversation with the agents, restarting the loop.
Figure 8. Continuing the conversation.
Optimizing the architecture
Building the system was one challenge. Making it production-ready was another.
Our initial prototype worked in controlled demos, but real-world usage revealed critical gaps. Users asked complex questions, conversations grew long, and edge cases exposed vulnerabilities. Here’s how we optimized the system to handle production demands while maintaining accuracy and safety.
Challenge 1: Excessive context
In multi-agent systems, context accumulates fast. Information is continuously passed from one agent to the next. Without careful management, excessive context and tokens cause performance degradation.
Our solution:
The orchestrator maintains a rich state throughout execution, tracking three critical elements:
Conversation and tooling history: Full message context for each agent.
Execution tracking: Which agents have run, current progress, and execution steps.
Agent responses: Structured responses from each agent, passed to subsequent agents.
This state is carefully managed to ensure each agent has the right context without overwhelming token limits.
Token tracking: Every message is counted using tiktoken, giving us real-time visibility into our token budget.
Intelligent summarization: When token limits are exceeded, earlier messages are automatically summarized while retaining information relevant to the original question. Recent messages and critical context remain unsummarized to preserve accuracy.
Retrieval-Augmented Generation (RAG) context pruning: We reduce context from tool outputs when enhancing prompts:
Instead of passing full code files to the Code Search Agent, we use smaller LLM models to extract the most relevant code snippets and a short description.
For database queries, we apply filters to retrieve only the top relevant results.
Handoffs Pattern: The previous agent returns its response to a central orchestrator. The orchestrator cleans the context, prunes unnecessary tokens, and invokes the next agent.
The result:
Agents can handle extended investigations without drowning in excessive context, maintaining performance even in complex, multi-turn conversations.
Challenge 2: Excessive tool usage
Our initial design presented a significant performance bottleneck due to excessive tool usage. Early models were equipped with a large and unwieldy set of over 30 distinct tools, each structured similarly to a generic API. Since tool calling is part of an agent’s prompt, agents had to process verbose tool descriptions and outputs, which degraded efficiency.
Our solution:
We focused on tool design based on real-world usage scenarios:
Included only the relevant portions required for decision-making.
Aggressively truncated verbose information from tool outputs.
Streamlined tool descriptions to be concise and actionable.
The result:
By significantly reducing the data load agents needed to process during inference, we achieved a substantial leap in system responsiveness and throughput.
Challenge 3: Risky code executions
AI agents with database access and code generation capabilities pose significant risks. Without proper safeguards, they could access sensitive PII data, execute dangerous SQL operations, run expensive queries, or generate breaking code changes. We needed to make the system safe.
Our solution:
We implemented multiple layers of safety to protect against misuse from both agents and users:
Layer 1: Input classification
Before any agent executes, the Classifier detects:
PII requests: Questions asking for personally identifiable information
Out-of-scope queries: Requests beyond the agent’s capabilities
Layer 2: SQL validation before execution
The Data Agent validates every query for:
PII column access: Checks against column metadata to ensure it doesn’t access confidential information.
Data definition and manipulation language (DDL/DML) operations: The agent doesn’t have access to DELETE, DROP, TRUNCATE, or UPDATE operations, but this check acts as an additional safeguard.
Slow queries: Detects missing partition filters or excessive date ranges that could cause expensive full-table scans.
Schema validation: Confirms tables and columns exist before execution.
Layer 3: Timeout protection
All database queries have strict execution limits to prevent runaway queries from impacting system performance.
Layer 4: Enhancement agent controls
For the Enhancement Agent, which generates code changes:
Cannot commit to master/main directly: All changes go through MRs.
Mandatory human review: A human reviewer must validate all inputs before execution.
Test environment first: Changes run in staging before production deployment.
The result:
A safe environment where AI agents can operate in production without compromising security or stability. Users and engineers trust the system because they know it has robust guardrails protecting critical data and systems.
Challenge 4: Ensuring user trust
Even with RAG and guardrails, AI agents aren’t perfect. Hallucinations, misinterpretations, and edge cases could erode user trust.
Our solution:
After generating a summarized response, the multi-agent system routes to human reviewers who can take five actions:
Approve: Post the response as-is and add a footnote that the response has been deemed accurate by a human reviewer.
Reject: Mark the response as incorrect and log it for improvement. The response will not be posted, protecting users from bad information.
Refine: Add a prompt to improve the summarized response from the sub-agents. The system regenerates the answer with additional guidance.
Re-route to Sub-Agents: Send the question to a specific agent with additional context. For example: “Data Agent, can you check the last 30 days instead of 7 days?”
Annotate: Provide structured feedback to the response, where it gets saved to a database for continuous improvement.
Figure 9. Human review.
Figure 10. Annotations.
The result:
This human-in-the-loop model ensures answers are accurate and reliable, increasing user trust in the responses. The annotations help us iteratively improve the model’s future responses.
Challenge 5: Balancing speed and quality
Our initial design withheld AI-generated responses until authorized by an engineering team member. This introduced a bottleneck in the response process, potentially leaving inquiries unresolved for extended periods, particularly during peak workload times.
Our solution:
We redesigned the process to allow responses to be posted without immediate human review, provided they are clearly and prominently marked as unreviewed. All posts can still be reviewed and modified by the on-call engineer as needed, but users get answers immediately rather than waiting.
The result:
This approach maintains a crucial balance between response speed and quality:
Engineers still review all responses to catch errors and improve the system.
Feedback loop remains intact for continuous learning.
Challenge 6: Closing the feedback loop
Collecting feedback through annotations was just the first step. Without systematic analysis, we had a gold mine of information about what worked and what didn’t, but we weren’t learning from it. Every rejected response was a lesson unlearned, every annotation a pattern unrecognized. We needed to close the loop.
Our solution:
We transformed annotations from passive records into an active improvement engine through five mechanisms:
Automated evaluation: Random annotations are pulled to create test cases for offline evaluation. This ensures the system is tested against real-world failure scenarios, not just synthetic test cases we invented.
Pattern analysis: We analyze annotations to identify systemic issues:
Is the Classifier consistently routing to the wrong agents?
Does a specific agent have quality issues?
Are certain types of queries prone to hallucinations?
Do particular table schemas cause confusion?
Quality metrics: Tracking annotation rates over time measures system reliability and identifies regression. If the rejection rate suddenly increases, we know something has changed that needs investigation.
Targeted improvements: Annotations guide where to focus development effort:
Improving prompts: Refining agent system prompts with better examples.
Adding guardrails: Enhancing input classification to catch problematic queries earlier.
Enhancing specific agents: Adding examples or tools to handle struggling query types.
Training data: Annotated failures can be used to:
Fine-tune models on domain-specific patterns.
Improve few-shot examples in prompts.
Build regression test suites from actual failures.
The result:
The system transformed from static to continuous learning. Every mistake became an opportunity for improvement, and the system got smarter with each interaction. We had data-driven insights guiding our optimization priorities, ensuring we focused on the highest-impact improvements.
Impact
The deployment of this multi-agent system yielded transformative results across key performance indicators, shifting the team’s entire operational dynamic.
Automated resolution:The bots now autonomously handle the majority of standard user inquiries and a significant portion of common enhancement requests.
Velocity gains: The time required to resolve issues has seen an order-of-magnitude reduction, effectively eliminating the support backlog. Simple inquiries are autonomously answered and brought to a resolution within minutes.
Productivity gains: The team has successfully reclaimed several full-time equivalents (FTE) worth of engineering bandwidth, shifting hundreds of hours from reactive support to proactive roadmap delivery.
With this newfound capacity unlocked, the data engineering team pivots from reactive support to proactive, high-value work, ultimately leading to “happier downstream users.”
Conclusions
Our journey from overwhelmed data engineers to a team empowered by AI agents revealed three core principles that made this transformation possible:
Multi-Agent architecture: Specialists over generalists
Specialized AI agents outperform a single generalist by mastering specific domains (e.g., data quality, code analysis). This modularity allows for independent improvement, easy additions, and clear responsibilities, boosting maintainability and flexibility.
Strategic human oversight: Building trust through transparency
Routing AI responses through human reviewers achieved rapid adoption through trust and continuous system improvement by generating annotated training feedback.
Focus on augmentation: Automating repetitive tasks
AI agents operate autonomously on repetitive tasks (context gathering, running queries, checking logs) with human oversight if needed, and collaborate with us in augmenting higher-value work: architectural decisions and building new capabilities.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.