Tag Archives: artificial intelligence

Enabling AI adoption at scale through enterprise risk management framework – Part 1

Post Syndicated from Milind Dabhole original https://aws.amazon.com/blogs/security/enabling-ai-adoption-at-scale-through-enterprise-risk-management-framework-part-1/

According to BCG research, 84% of executives view responsible AI as a top management responsibility, yet only 25% of them have programs that fully address it. Responsible AI can be achieved through effective governance, and with the rapid adoption of generative AI, this governance has become a business imperative, not just an IT concern. By implementing systematic governance approaches at the enterprise level, organizations can balance innovation with control, effectively managing the risks while harnessing the transformative potential of generative AI.

While generative AI technologies offer compelling capabilities, they also introduce new types of risks that need business oversight and management. Financial institutions face real challenges—AI-driven financial analysis tools could make investment recommendations based on biased data, leading to significant losses, while generative AI-powered customer service systems might inadvertently expose confidential customer information. The unprecedented scale and speed at which generative AI operates makes robust business controls essential. However, with the right governance approach and strategic oversight, these risks are manageable.

Part 1 of this two-part blog post guides business leaders, Chief Risk Officers (CROs), and Chief Internal Auditors (CIAs) through three critical questions:

  • What specific or unique risks does generative AI introduce and how can they be managed?
  • How should your enterprise risk management framework (ERMF) evolve to support generative AI adoption?
  • How can you build sustainable generative AI governance in an ever-changing world—what should be on your checklist?

To address these questions, organizations can use established frameworks and standards including:

These frameworks provide valuable guidance for organizations looking to implement responsible and governed AI practices.

Role of GRC leaders, CROs, and CIAs

Governance, risk and control (GRC) functions led by business leaders, CROs and CIAs are well-positioned to advance generative AI innovation in financial services institutions. These functions have successfully managed complex risks in banks for years, and their existing expertise, proven approaches, and established risk frameworks provide a strong foundation for guiding generative AI adoption. They collaborate across the three lines of defense: business leaders making implementation decisions and managing associated risks (first line), risk and compliance functions providing frameworks and oversight (second line), and internal audit providing independent assurance (third line).

If generative AI risks, both perceived and real, are managed through enterprise-wide governance practices rather than isolated project-by-project approaches, organizations can use the advantages offered by generative AI over the long term. This requires integration with the ERMF, with some practices fitting into existing structures while others need deliberate adjustments to ERMF itself to address generative AI’s unique characteristics.

New frontiers in generative AI risk management

The traditional risk landscape at the enterprise level was based on a paradigm in which risks are predicted from past exposures. Preventive controls help stop unwanted things from happening, detective controls discover when bad things slip through the preventive controls, and corrective controls take remediation actions.

Much of this paradigm is still valid in the world of generative AI. For example, access to generative AI applications needs to be managed carefully to avoid unauthorized use. All three types of the preceding controls should help prevent unauthorized use, identify potential breaches, and remedy unauthorized access when detected.

However, additional focus and attention are required in the following areas when implementing generative AI solutions:

  • Non-deterministic outputs – The non-deterministic nature of generative AI outputs poses a specific challenge. While the probabilistic nature of these systems is often useful, the risk of inaccurate output from the black box can have serious business implications, and organizations need to take conscious actions to address these risks. Organizations can address this through Amazon Bedrock Guardrails Automated Reasoning checks, which use mathematically sound verification to help prevent factual errors and hallucinations.
  • Deepfake threat – Generative AI’s ability to create authentic-looking images and documents extends beyond traditional fraudulent activities. It elevates the threat to an entirely new level, creating eerily realistic content with unprecedented ease—hence the term deepfake. This poses significant challenges for organizations in verifying document authenticity, particularly in processes like Know Your Customer (KYC).
  • Layered opacity – While enterprises are learning about generative AI, they must address risks from multi-layered AI systems where each layer generates content and makes decisions based on potentially unexplainable models, hampering traceability. For example, consider generative AI outputs from a third-party system serving as inputs to internal AI systems, creating a chain of interdependent decisions. This lack of transparency in critical decisions affecting organizational performance and customer treatment could have profound implications for enterprise trustworthiness, brand reputation, and regulatory compliance.

The following table outlines key generative AI risk areas and their potential business impacts. In Part 2, we explain how organizations can address these risks through their ERMF. Effectively managing these risks through enterprise-wide governance not only protects the organization but also forms the foundation for responsible AI adoption. Robust risk management and governance are essential prerequisites for achieving responsible AI outcomes.

For a comprehensive foundation in responsible AI implementation, see the AWS Responsible Use of AI Guide, which aligns with the governance principles that we discuss throughout this article.

Risk area Description Potential risk impact
Fairness Are the underlying data and algorithms fair and unbiased? Are the outputs leading to fair outcomes for different groups of stakeholders?
  • Discrimination lawsuits
  • Loss of trust
  • Business loss because of exclusion of segments
Explainability Can stakeholders understand the black box behavior and evaluate system outputs?
  • Legal liabilities and regulatory sanctions due to inability to explain decisions
  • Incorrect business decisions
Privacy and security Are the systems aligned with privacy regulations and security requirements?
  • Fines arising from data breaches
  • Loss of trust
  • Damage because of security incidents
Safety Are there controls to help prevent harmful system output and misuse?
  • Harmful content generation
  • Customer harm
  • Reputational damage
Controllability Are there mechanisms to monitor and steer AI system behaviour, including detection of model and data drifts?
  • Undetected degradation of service
  • Business disruption because of unreliable decisions
  • Customer harm
  • Inefficiencies arising from remediation
Veracity and robustness Can the system maintain correct outputs even with unexpected or adversarial inputs?
  • Incorrect business decisions
  • System failures under stress
  • Loss of operational reliability
Governance Are there documented accountabilities across the AI supply chain including model providers and deployers? Are users adequately trained to use systems?
  • Confusion in crisis management
  • Personal liability for executives
  • Regulatory censure for governance failures
  • System misuse by untrained staff
Transparency Can stakeholders make informed choices about their engagement with the AI system?
  • Loss of customer trust
  • Regulatory non-compliance
  • Stakeholder dissatisfaction

Remitly’s implementation of Amazon Bedrock Guardrails to protect customer personally identifiable information (PII) data and reduce hallucinations demonstrates how financial institutions can effectively manage privacy and veracity risks in generative AI applications, addressing several of the risk areas outlined above.

Conclusion

In this post, we introduced the critical importance of responsible AI governance for enterprises adopting generative AI at scale. We explored the unique risks that generative AI presents, including non-deterministic outputs, deepfake threats, and layered opacity. We outlined key risk areas such as fairness, explainability, privacy and security, safety, controllability, veracity and robustness, governance, and transparency. These risks underscore the need for a robust enterprise risk management framework tailored to the challenges of generative AI.

We emphasized the crucial role of GRC leaders, CROs, and CIAs in advancing generative AI innovation while managing associated risks. By using established frameworks like the AWS Cloud Adoption Framework for AI, ISO/IEC 42001, and the NIST AI Risk Management Framework, organizations can implement responsible and governed AI practices.

In Part 2 of this series, we explore how organizations can adapt their enterprise risk management framework to address these risks effectively, including specific considerations for cloud and generative AI implementation. We’ll provide detailed guidance on making your ERMF generative AI-ready and outline practical steps for sustainable risk management.


Additional reading

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Milind Dabhole

Milind Dabhole

Milind is a Principal Customer Solutions Manager focusing on enterprise innovation and risk governance. Before joining AWS, he spent over two decades in financial services, holding senior roles across first, second, and third lines of defense at global financial institutions. At AWS, he advises C-suite executives on cloud and AI transformation strategies that balance innovation with robust controls.

Stephen James Martin

Stephen James Martin

Steve is the Head of Financial Services Compliance and Security for EMEA and APAC. Steve Joined AWS after working for over 20 years in financial service in senior leadership roles with responsibility across Asia, the Middle East, and Europe. At AWS, he supports customers as they use the scale, security, and agility of AWS to transform the industry.

Teaching Experience AI: Lessons from educators in Mexico

Post Syndicated from Liz Eaton original https://www.raspberrypi.org/blog/teaching-experience-ai-lessons-from-educators-in-mexico/

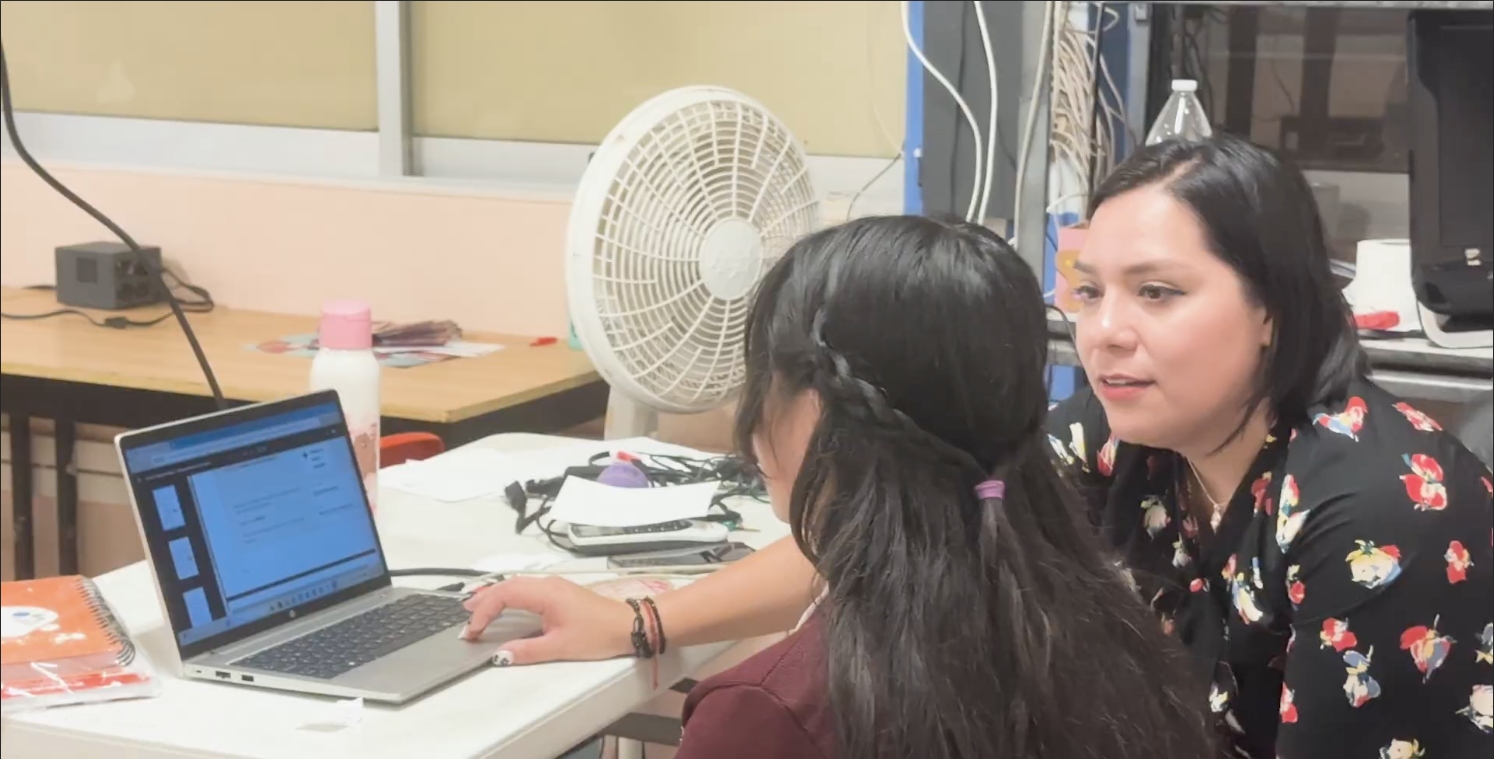
In classrooms across Mexico, a transformation is unfolding. The Experience AI programme isn’t just teaching students about artificial intelligence, it’s empowering teachers and learners to explore, question, and create with it. By equipping educators with accessible tools and sparking curiosity among students, the initiative is shaping a new generation ready to use AI responsibly and creatively.

Teacher at the front of the classroom

Educators like Guadalupe Cortes, Lilia Violeta Garvia Sanchez, Ines Martinez, and Ana Judith Zavaleta are at the forefront of this shift. Their experiences reveal just how transformative Experience AI has become.

From fear to fascination: Demystifying AI

For many, AI can feel abstract, something from science fiction. Science and math teacher Lilia Violeta Garvia Sanchez remembers that both she and her students once viewed AI as “robots that would take over the world.” Fear gave way to fascination, however, once Experience AI entered the classroom.

Through hands-on lessons, students quickly discovered AI as a practical tool rather than a threat. “I’ve seen a change in the students,” Lilia explains. “They were afraid at first, but now they’re curious and engaged.”

Technology teacher Ines Martinez admits she was also surprised: “I thought the language would be more technical or complex, but it was pleasantly accessible — and very useful.”

Equipping educators with tools that work

A defining strength of Experience AI is its adaptability. Teachers can tailor materials to fit their classrooms while still leaning on the program’s robust foundation.

Guadalupe Cortes points to the built-in glossary as a game-changer: “It was really helpful for me.” She values being able to choose what fits her teaching to keep it relevant: “I selected certain parts to connect with projects I was already running.”

Sparking critical thinking and ethical awareness

Experience AI pushes students to think deeply about the ethics and implications of AI.

In Ines’s class, students raised concerns about water use in data centres and debated how to protect their digital identities. They weren’t just learning facts, they were making connections to real-world issues.

Educator supporting young learner in the classroom

Another teacher, Ileana Beurini, described an exercise where students asked different AI models the same political question. When answers varied, they discussed bias and the importance of consulting multiple sources. In another activity, searching images of “worker” led to a conversation about gender equity in technology.

As Ines puts it: “They don’t want it to do all the thinking for them. They said it should be a support — a tool to generate better information, not to replace reasoning or reflection.”

Transforming engagement and performance

The impact on student motivation has been striking. For Ana Judith Zavaleta, the shift was clear: “They’re much more hands-on now — they don’t rely as much on textbooks or theory.” One student who typically struggled academically became one of the most enthusiastic participants, even passing where he previously failed.

Guadalupe Cortes has seen similar enthusiasm: “They’re finding a real purpose in using AI for their own benefit.” At an entrepreneurship fair, her students applied AI concepts to improve their projects, proof that these lessons extend far beyond the classroom.

A call to action for educators

The teachers’ message is unanimous: embrace AI.

“We should give it a try,” urges Lilia. “Just because we’re teachers doesn’t mean we have to know everything. The world is evolving every single day, and we need to innovate with our students so they feel motivated to keep learning.”

Young learners work on the classroom wall

For Ines, the takeaway is simple but powerful: “Take the risk — really, take the chance to learn. Just like the internet became essential, AI will become part of our daily lives and necessary for all areas of teaching — and life itself.”

More than just a set of resources

Experience AI is more than a set of resources, it’s a movement preparing students to navigate the future with curiosity, critical thinking, and ethical awareness. By igniting minds in Mexico, it’s helping to cultivate responsible digital citizens who will shape not just their classrooms, but the world beyond them.

For more information about Experience AI, visit our website: rpf.io/experienceai

For more information about our global Experience AI partner in Mexico, visit: educacionparacompartir.org

The post Teaching Experience AI: Lessons from educators in Mexico appeared first on Raspberry Pi Foundation.

AWS named as a Leader in the 2025 Gartner Magic Quadrant for AI Code Assistants

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/aws-named-as-a-leader-in-the-2025-gartner-magic-quadrant-for-ai-code-assistants/

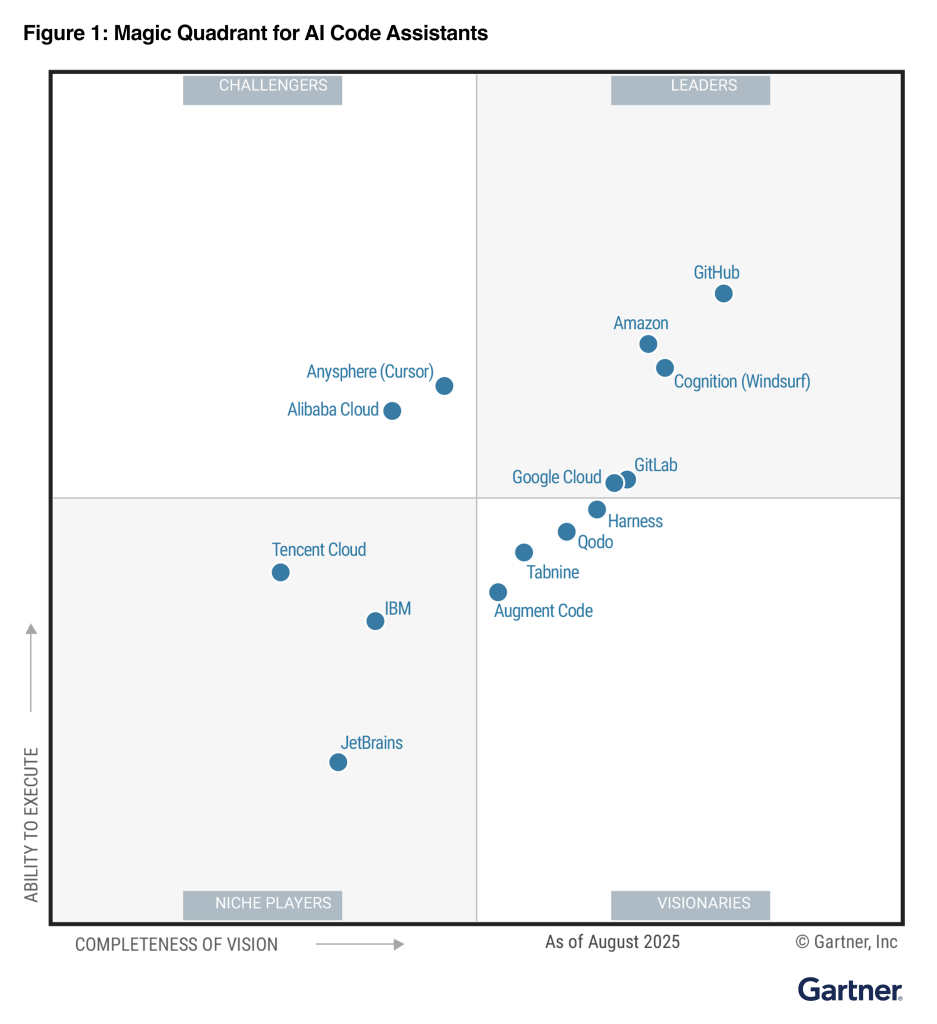
We are excited to share that AWS has been named a Leader in the 2025 Gartner Magic Quadrant for AI Code Assistants for the second year in row. This recognition highlights for us Amazon Q Developer’s commitment to innovation and delivering exceptional customer experiences. We believe this Leader placement showcases our rapid pace of innovation, which makes the whole software development lifecycle easier and increases developer productivity with enterprise-grade access controls and security. We are honored to be recognized by Gartner and are committed to continuing to innovate on behalf of our customers.

A Gartner Magic Quadrant chart titled 'Magic Quadrant for AI Code Assistants' showing the positioning of various companies across four quadrants: Leaders, Challengers, Visionaries, and Niche Players. Companies like GitHub, Amazon, and Google Cloud are prominently positioned in the Leaders quadrant, while others like JetBrains appear in the Visionaries section. The chart plots vendors based on their 'Ability to Execute' (y-axis) and 'Completeness of Vision' (x-axis). Dated August 2025.

The Gartner Magic Quadrant evaluated AI code assistant providers based on their Ability to Execute and Completeness of Vision. Our innovations throughout the software life cycle (SDLC) include code generation, troubleshooting, transformation, cost optimization, and vulnerability scanning.

Leaders in this Magic Quadrant for AI Code Assistants continue to set the benchmark for end-to-end developer enablement through advanced AI capabilities. They consistently integrate cutting-edge models into robust, agentic workflows that enhance productivity, code quality, and security across the SDLC. These vendors exhibit a sharp understanding of enterprise needs, translating customer feedback into iterative improvements and differentiated innovation — such as long-context reasoning, hybrid deployment flexibility, and seamless integration across IDEs and DevSecOps platforms. Leaders also stand out through their operational maturity, supporting global enterprises with scalable infrastructure, regulatory compliance, and strong service-level reliability. Their growing ecosystems, deepening product integration, and strategic clarity ensure sustained influence across diverse developer and enterprise environments.

Access the complete 2025 Gartner Magic Quadrant for AI Code Assistants report to learn more and get started with Amazon Q Developer today.

Qwen models are now available in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/qwen-models-are-now-available-in-amazon-bedrock/

Today we are adding Qwen models from Alibaba in Amazon Bedrock. With this launch, Amazon Bedrock continues to expand model choice by adding access to Qwen3 open weight foundation models (FMs) in a full managed, serverless way. This release includes four models: Qwen3-Coder-480B-A35B-Instruct, Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B (Dense). Together, these models feature both mixture-of-experts (MoE) and dense architectures, providing flexible options for different application requirements.

Amazon Bedrock provides access to industry-leading FMs through a unified API without requiring infrastructure management. You can access models from multiple model providers, integrate models into your applications, and scale usage based on workload requirements. With Amazon Bedrock, customer data is never used to train the underlying models. With the addition of Qwen3 models, Amazon Bedrock offers even more options for use cases like:

  • Code generation and repository analysis with extended context understanding
  • Building agentic workflows that orchestrate multiple tools and APIs for business automation
  • Balancing AI costs and performance using hybrid thinking modes for adaptive reasoning

Qwen3 models in Amazon Bedrock
These four Qwen3 models are now available in Amazon Bedrock, each optimized for different performance and cost requirements:

  • Qwen3-Coder-480B-A35B-Instruct – This is a mixture-of-experts (MoE) model with 480B total parameters and 35B active parameters. It’s optimized for coding and agentic tasks and achieves strong results in benchmarks such as agentic coding, browser use, and tool use. These capabilities make it suitable for repository-scale code analysis and multistep workflow automation.
  • Qwen3-Coder-30B-A3B-Instruct – This is a MoE model with 30B total parameters and 3B active parameters. Specifically optimized for coding tasks and instruction-following scenarios, this model demonstrates strong performance in code generation, analysis, and debugging across multiple programming languages.
  • Qwen3-235B-A22B-Instruct-2507 – This is an instruction-tuned MoE model with 235B total parameters and 22B active parameters. It delivers competitive performance across coding, math, and general reasoning tasks, balancing capability with efficiency.
  • Qwen3-32B (Dense) – This is a dense model with 32B parameters. It is suitable for real-time or resource-constrained environments such as mobile devices and edge computing deployments where consistent performance is critical.

Architectural and functional features in Qwen3
The Qwen3 models introduce several architectural and functional features:

MoE compared with dense architectures – MoE models such as Qwen3-Coder-480B-A35B, Qwen3-Coder-30B-A3B-Instruct, and Qwen3-235B-A22B-Instruct-2507, activate only part of the parameters for each request, providing high performance with efficient inference. The dense Qwen3-32B activates all parameters, offering more consistent and predictable performance.

Agentic capabilities – Qwen3 models can handle multi-step reasoning and structured planning in one model invocation. They can generate outputs that call external tools or APIs when integrated into an agent framework. The models also maintain extended context across long sessions. In addition, they support tool calling to allow standardized communication with external environments.

Hybrid thinking modes – Qwen3 introduces a hybrid approach to problem-solving, which supports two modes: thinking and non-thinking. The thinking mode applies step-by-step reasoning before delivering the final answer. This is ideal for complex problems that require deeper thought. Whereas the non-thinking mode provides fast and near-instant responses for less complex tasks where speed is more important than depth. This helps developers manage performance and cost trade-offs more effectively.

Long-context handling – The Qwen3-Coder models support extended context windows, with up to 256K tokens natively and up to 1 million tokens with extrapolation methods. This allows the model to process entire repositories, large technical documents, or long conversational histories within a single task.

When to use each model
The four Qwen3 models serve distinct use cases. Qwen3-Coder-480B-A35B-Instruct is designed for complex software engineering scenarios. It’s suited for advanced code generation, long-context processing such as repository-level analysis, and integration with external tools. Qwen3-Coder-30B-A3B-Instruct is particularly effective for tasks such as code completion, refactoring, and answering programming-related queries. If you need versatile performance across multiple domains, Qwen3-235B-A22B-Instruct-2507 offers a balance, delivering strong general-purpose reasoning and instruction-following capabilities while leveraging the efficiency advantages of its MoE architecture. Qwen3-32B (Dense) is appropriate for scenarios where consistent performance, low latency, and cost optimization are important.

Getting started with Qwen models in Amazon Bedrock
To begin using Qwen models, in the Amazon Bedrock console, I choose Model Access from the Configure and learn section of the navigation pane. I then navigate to the Qwen models to request access. In the Chat/Text Playground section of the navigation pane, I can quickly test the new Qwen models with my prompts.

To integrate Qwen3 models into my applications, I can use any AWS SDKs. The AWS SDKs include access to the Amazon Bedrock InvokeModel and Converse API. I can also use these model with any agentic framework that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore. For example, here’s the Python code of a simple agent with tool access built using Strands Agents:

from strands import Agent
from strands_tools import calculator

agent = Agent(
    model="qwen.qwen3-coder-480b-instruct-v1:0",
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 9")

with open("function.py", 'r') as f:
    my_function_code = f.read()

agent(f"Help me optimize this Python function for better performance:\n\n{my_function_code}")

Now available
Qwen models are available today in the following AWS Regions:

  • Qwen3-Coder-480B-A35B-Instruct is available in the US West (Oregon), Asia Pacific (Mumbai, Tokyo), and Europe (London, Stockholm) Regions.
  • Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B are available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Tokyo), Europe (Ireland, London, Milan, Stockholm), and South America (São Paulo) Regions.

Check the full Region list for future updates. You can start testing and building immediately without infrastructure setup or capacity planning. To learn more, visit the Qwen in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Try Qwen models on the Amazon Bedrock console now, and offer feedback through AWS re:Post for Amazon Bedrock or your typical AWS Support channels.

— Danilo

DeepSeek-V3.1 model now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-v3-1-now-available-in-amazon-bedrock/

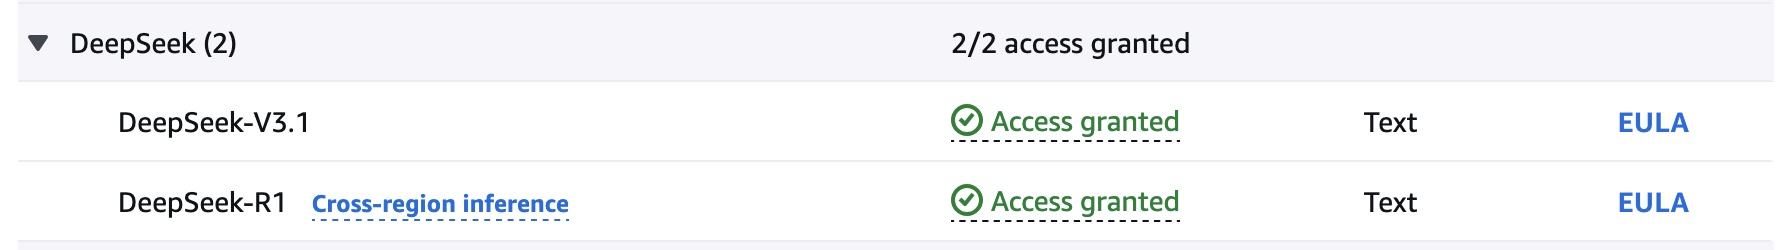
In March, Amazon Web Services (AWS) became the first cloud service provider to deliver DeepSeek-R1 in a serverless way by launching it as a fully managed, generally available model in Amazon Bedrock. Since then, customers have used DeepSeek-R1’s capabilities through Amazon Bedrock to build generative AI applications, benefiting from the Bedrock’s robust guardrails and comprehensive tooling for safe AI deployment.

Today, I am excited to announce DeepSeek-V3.1 is now available as a fully managed foundation model in Amazon Bedrock. DeepSeek-V3.1 is a hybrid open weight model that switches between thinking mode (chain-of-thought reasoning) for detailed step-by-step analysis and non-thinking mode (direct answers) for faster responses.

According to DeepSeek, the thinking mode of DeepSeek-V3.1 achieves comparable answer quality with better results, stronger multi-step reasoning for complex search tasks, and big gains in thinking efficiency compared with DeepSeek-R1-0528.

Benchmarks DeepSeek-V3.1 DeepSeek-R1-0528
Browsecomp 30.0 8.9
Browsecomp_zh 49.2 35.7
HLE 29.8 24.8
xbench-DeepSearch 71.2 55.0
Frames 83.7 82.0
SimpleQA 93.4 92.3
Seal0 42.6 29.7
SWE-bench Verified 66.0 44.6
SWE-bench Multilingual 54.5 30.5
Terminal-Bench 31.3 5.7
(c)
https://api-docs.deepseek.com/news/news250821

DeepSeek-V3.1 model performance in tool usage and agent tasks has significantly improved through post-training optimization compared to previous DeepSeek models. DeepSeek-V3.1 also supports over 100 languages with near-native proficiency, including significantly improved capability in low-resource languages lacking large monolingual or parallel corpora. You can build global applications to deliver enhanced accuracy and reduced hallucinations compared to previous DeepSeek models, while maintaining visibility into its decision-making process.

Here are your key use cases using this model:

  • Code generation – DeepSeek-V3.1 excels in coding tasks with improvements in software engineering benchmarks and code agent capabilities, making it ideal for automated code generation, debugging, and software engineering workflows. It performs well on coding benchmarks while delivering high-quality results efficiently.
  • Agentic AI tools – The model features enhanced tool calling through post-training optimization, making it strong in tool usage and agentic workflows. It supports structured tool calling, code agents, and search agents, positioning it as a solid choice for building autonomous AI systems.
  • Enterprise applications – DeepSeek models are integrated into various chat platforms and productivity tools, enhancing user interactions and supporting customer service workflows. The model’s multilingual capabilities and cultural sensitivity make it suitable for global enterprise applications.

As I mentioned in my previous post, when implementing publicly available models, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results in terms of data security, responsible AI, and model evaluation.

You can access the enterprise-grade security features of Amazon Bedrock and implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. You can also evaluate and compare models to identify the optimal model for your use cases by using Amazon Bedrock model evaluation tools.

Get started with the DeepSeek-V3.1 model in Amazon Bedrock
If you’re new to using the DeepSeek-V3.1 model, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-V3.1 model, request access for DeepSeek-V3.1 in the DeepSeek section. You’ll then be granted access to the model in Amazon Bedrock.

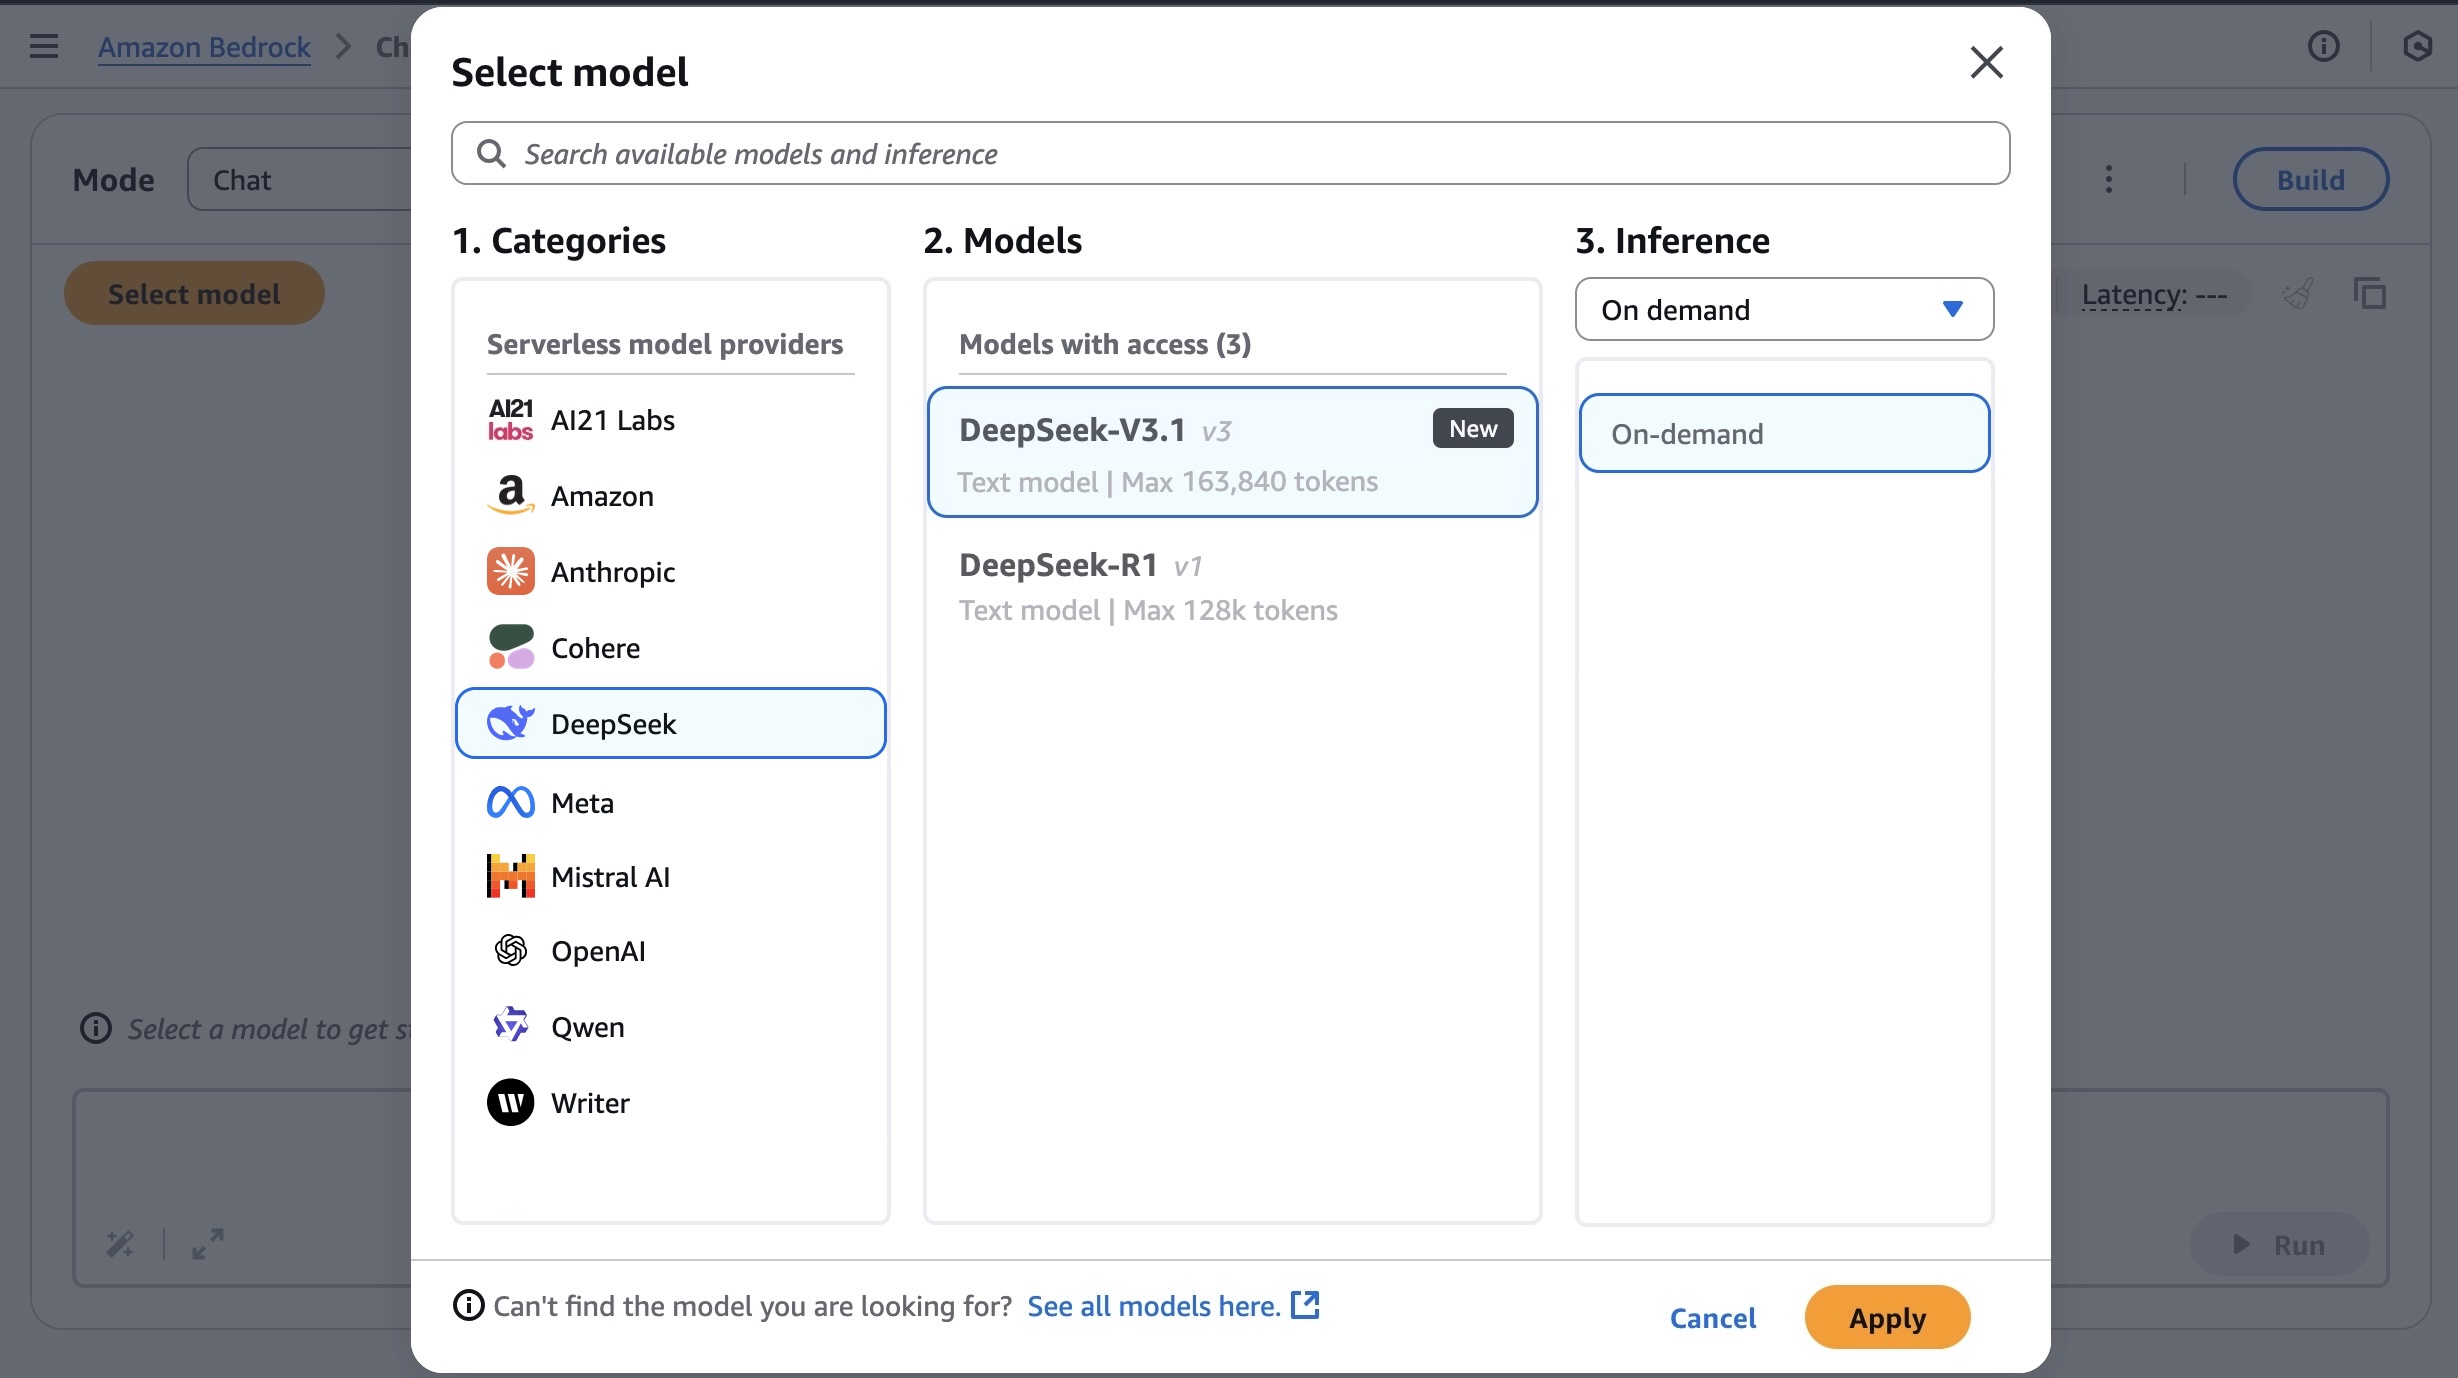
Next, to test the DeepSeek-V3.1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-V3.1 as the model. Then choose Apply.

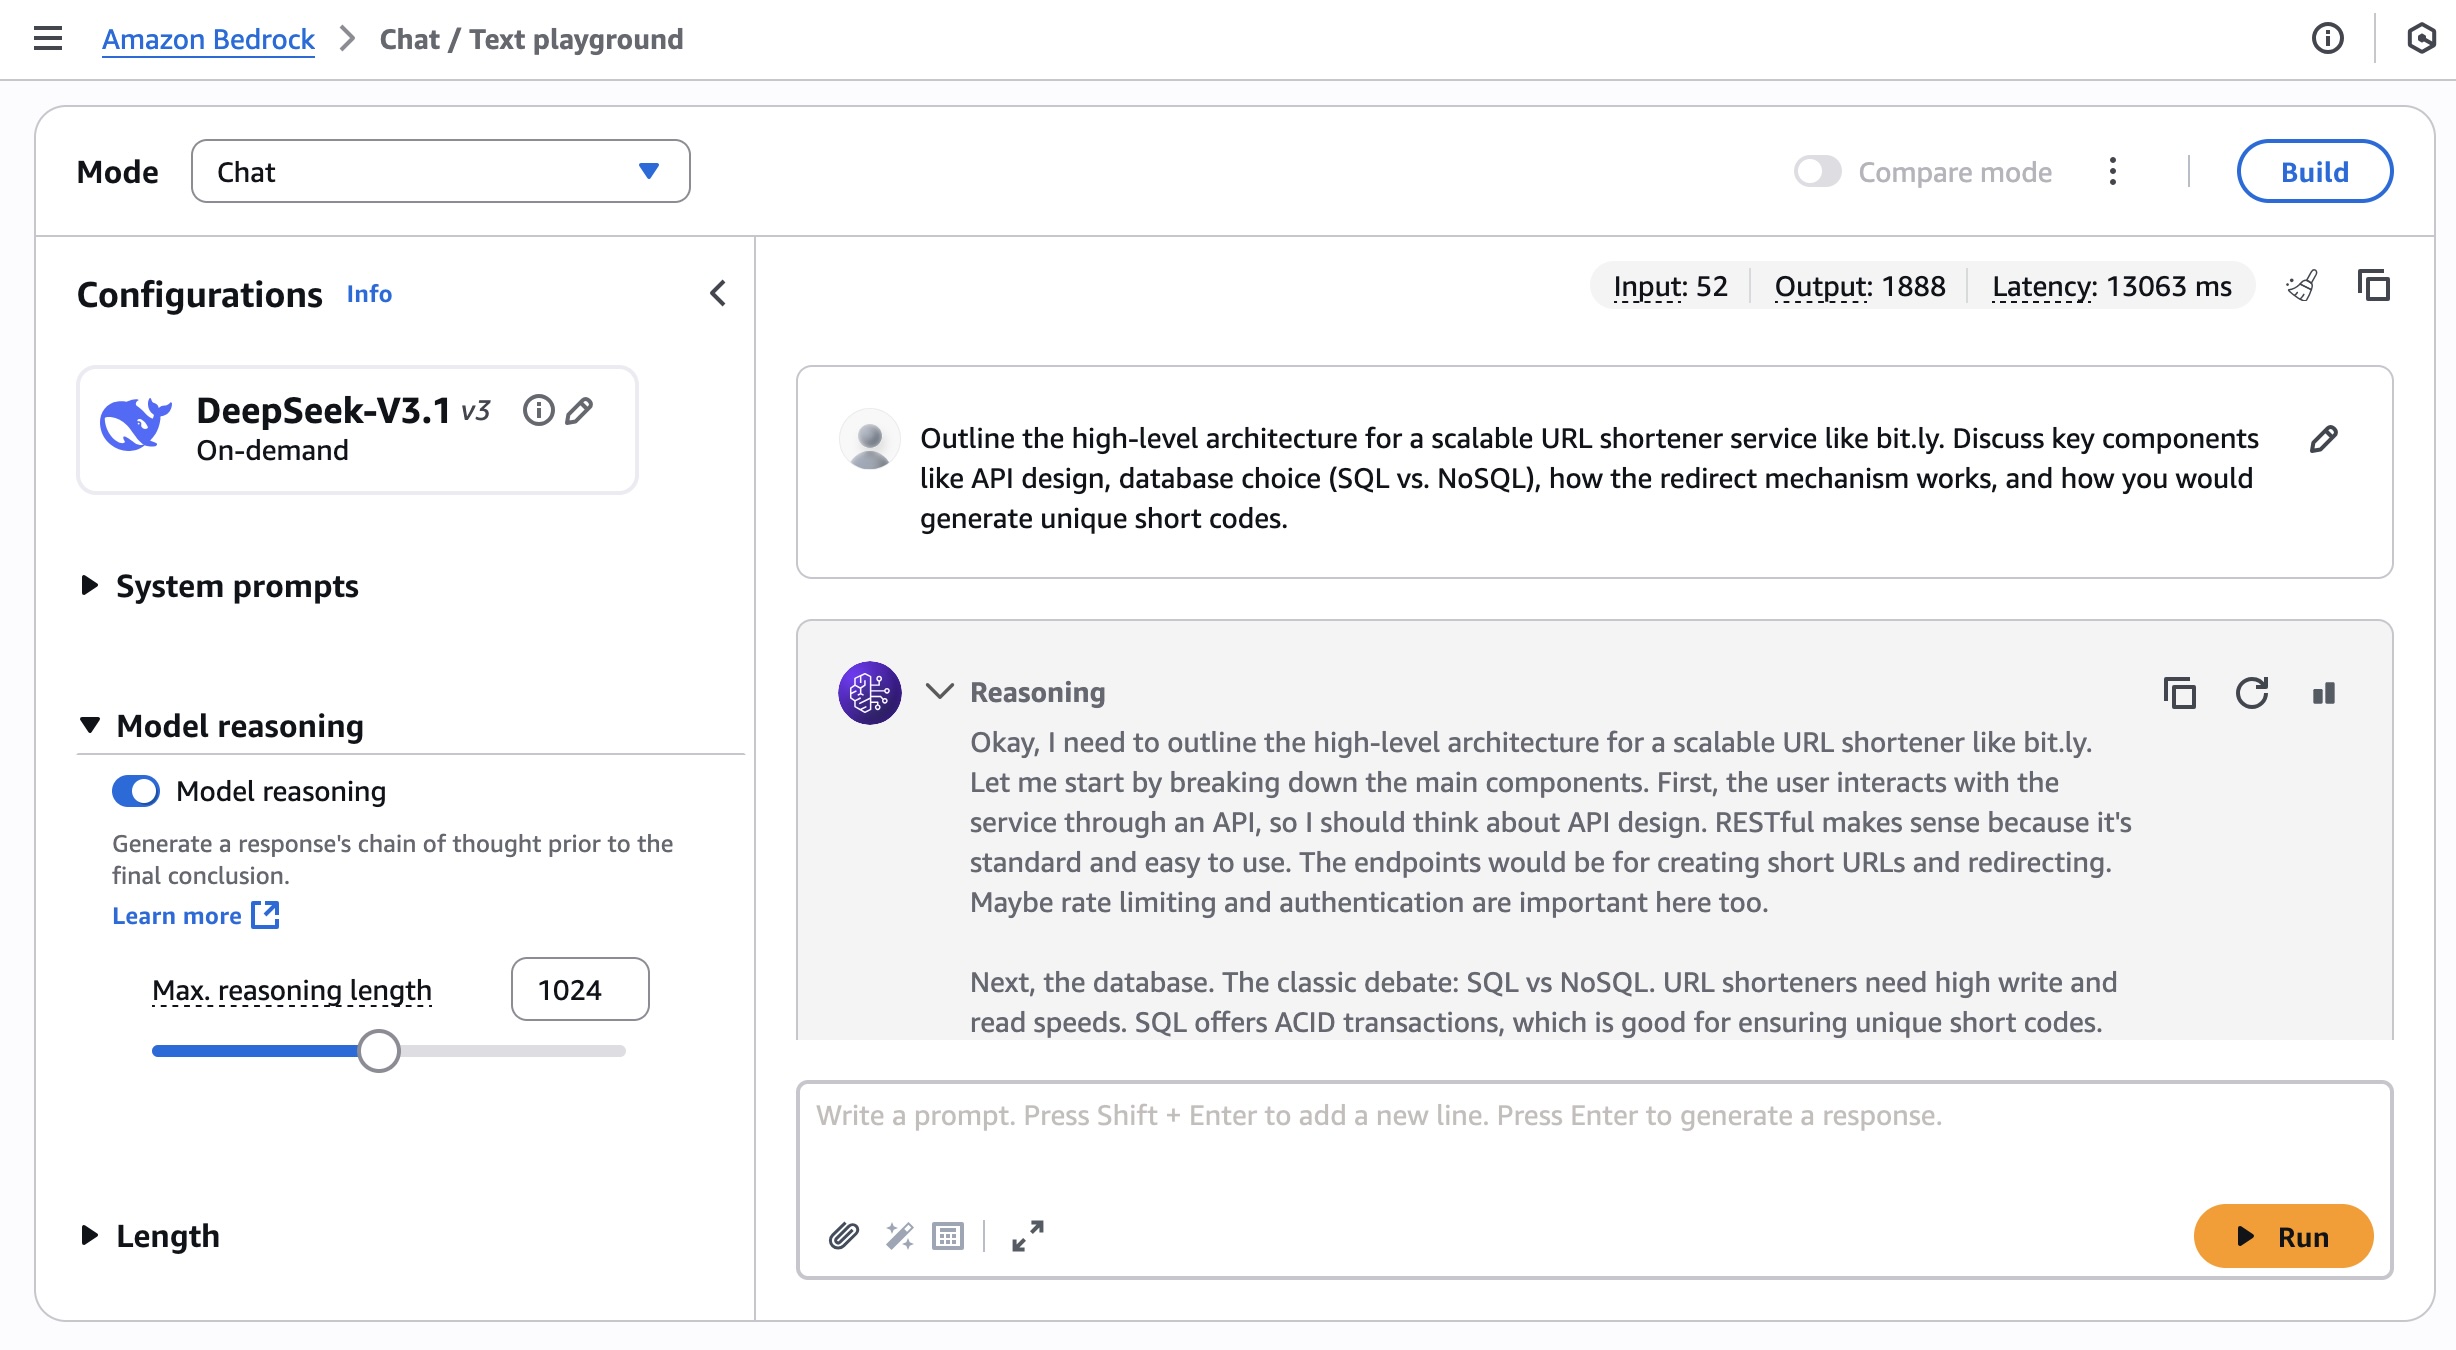
Using the selected DeepSeek-V3.1 model, I run the following prompt example about technical architecture decision.

Outline the high-level architecture for a scalable URL shortener service like bit.ly. Discuss key components like API design, database choice (SQL vs. NoSQL), how the redirect mechanism works, and how you would generate unique short codes.

You can turn the thinking on and off by toggling Model reasoning mode to generate a response’s chain of thought prior to the final conclusion.

You can also access the model using the AWS Command Line Interface (AWS CLI) and AWS SDK. This model supports both the InvokeModel and Converse API. You can check out a broad range of code examples for multiple use cases and a variety of programming languages.

To learn more, visit DeepSeek model inference parameters and responses in the AWS documentation.

Now available
DeepSeek-V3.1 is now available in the US West (Oregon), Asia Pacific (Tokyo), Asia Pacific (Mumbai), Europe (London), and Europe (Stockholm) AWS Regions. Check the full Region list for future updates. To learn more, check out the DeepSeek in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give the DeepSeek-V3.1 model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Minimize AI hallucinations and deliver up to 99% verification accuracy with Automated Reasoning checks: Now available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/minimize-ai-hallucinations-and-deliver-up-to-99-verification-accuracy-with-automated-reasoning-checks-now-available/

Today, I’m happy to share that Automated Reasoning checks, a new Amazon Bedrock Guardrails policy that we previewed during AWS re:Invent, is now generally available. Automated Reasoning checks helps you validate the accuracy of content generated by foundation models (FMs) against a domain knowledge. This can help prevent factual errors due to AI hallucinations. The policy uses mathematical logic and formal verification techniques to validate accuracy, providing definitive rules and parameters against which AI responses are checked for accuracy.

This approach is fundamentally different from probabilistic reasoning methods which deal with uncertainty by assigning probabilities to outcomes. In fact, Automated Reasoning checks delivers up to 99% verification accuracy, providing provable assurance in detecting AI hallucinations while also assisting with ambiguity detection when the output of a model is open to more than one interpretation.

With general availability, you get the following new features:

  • Support for large documents in a single build, up to 80K tokens – Process extensive documentation; we found this can add up to 100 pages of content
  • Simplified policy validation – Save your validation tests and run them repeatedly, making it easier to maintain and verify your policies over time
  • Automated scenario generation – Create test scenarios automatically from your definitions, saving time and effort while helping make coverage more comprehensive
  • Enhanced policy feedback – Provide natural language suggestions for policy changes, simplifying the way you can improve your policies
  • Customizable validation settings – Adjust confidence score thresholds to match your specific needs, giving you more control over validation strictness

Let’s see how this works in practice.

Creating Automated Reasoning checks in Amazon Bedrock Guardrails
To use Automated Reasoning checks, you first encode rules from your knowledge domain into an Automated Reasoning policy, then use the policy to validate generated content. For this scenario, I’m going to create a mortgage approval policy to safeguard an AI assistant evaluating who can qualify for a mortgage. It is important that the predictions of the AI system do not deviate from the rules and guidelines established for mortgage approval. These rules and guidelines are captured in a policy document written in natural language.

In the Amazon Bedrock console, I choose Automated Reasoning from the navigation pane to create a policy.

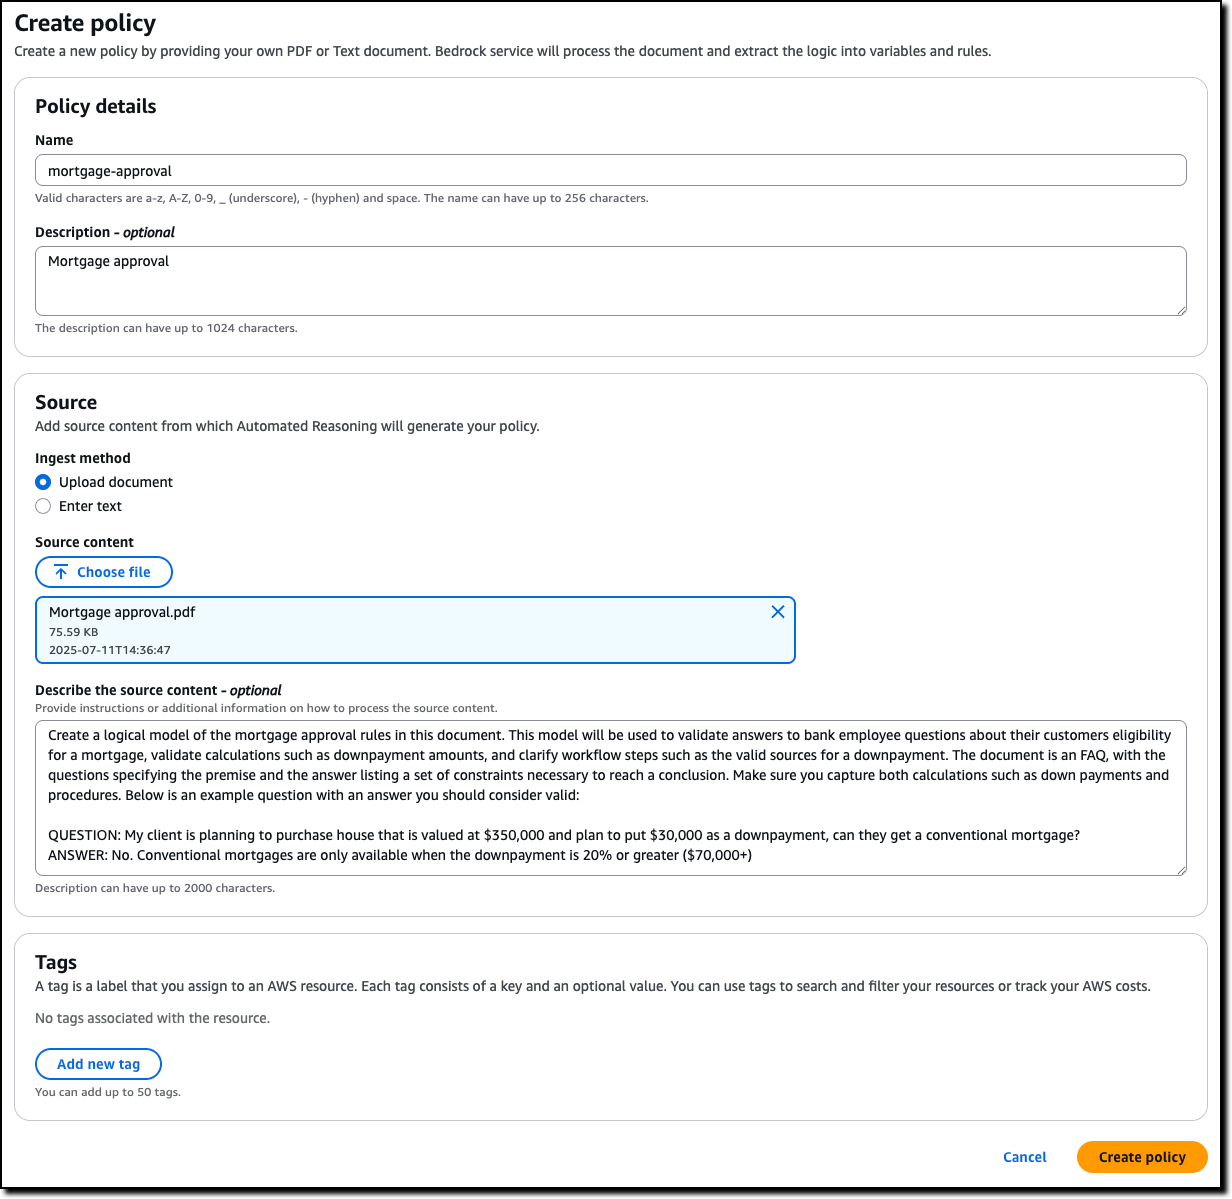
I enter name and description of the policy and upload the PDF of the policy document. The name and description are just metadata and do not contribute in building the Automated Reasoning policy. I describe the source content to add context on how it should be translated into formal logic. For example, I explain how I plan to use the policy in my application, including sample Q&A from the AI assistant.

Consoel screenshot.

When the policy is ready, I land on the overview page, showing the policy details and a summary of the tests and definitions. I choose Definitions from the dropdown to examine the Automated Reasoning policy, made of rules, variables, and types that have been created to translate the natural language policy into formal logic.

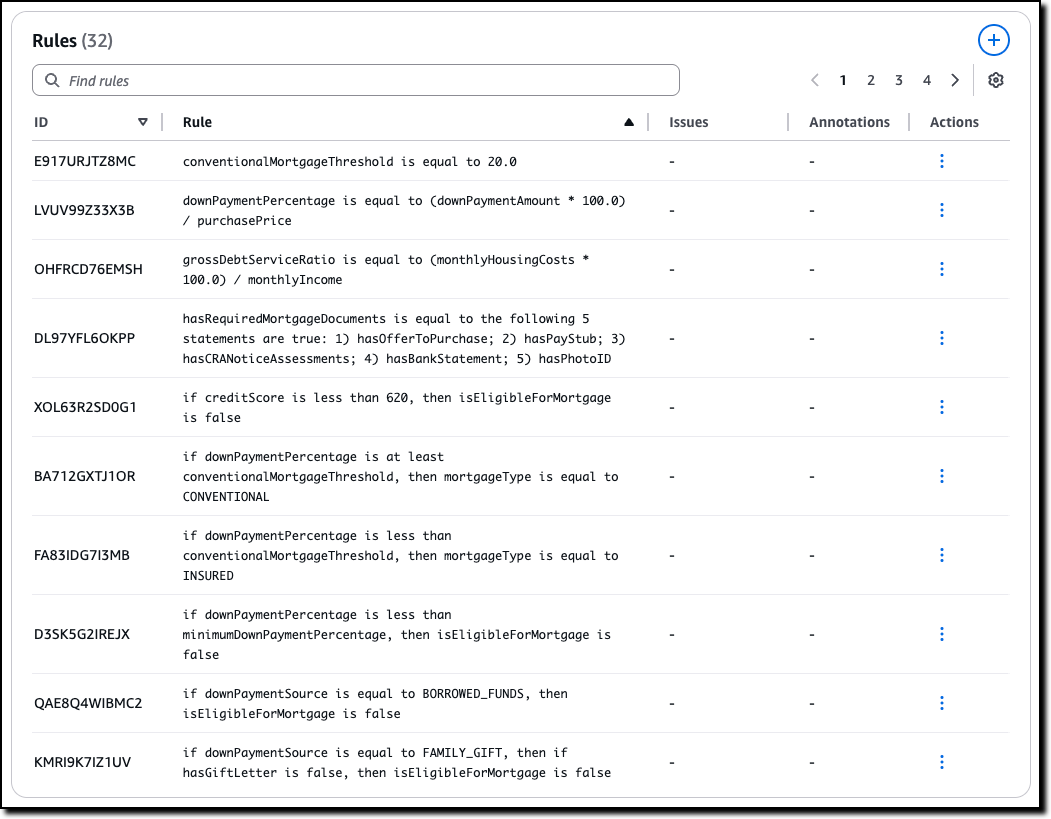
The Rules describe how variables in the policy are related and are used when evaluating the generated content. For example, in this case, which are the thresholds to apply and how some of the decisions are taken. For traceability, each rule has its own unique ID.

Console screenshot.

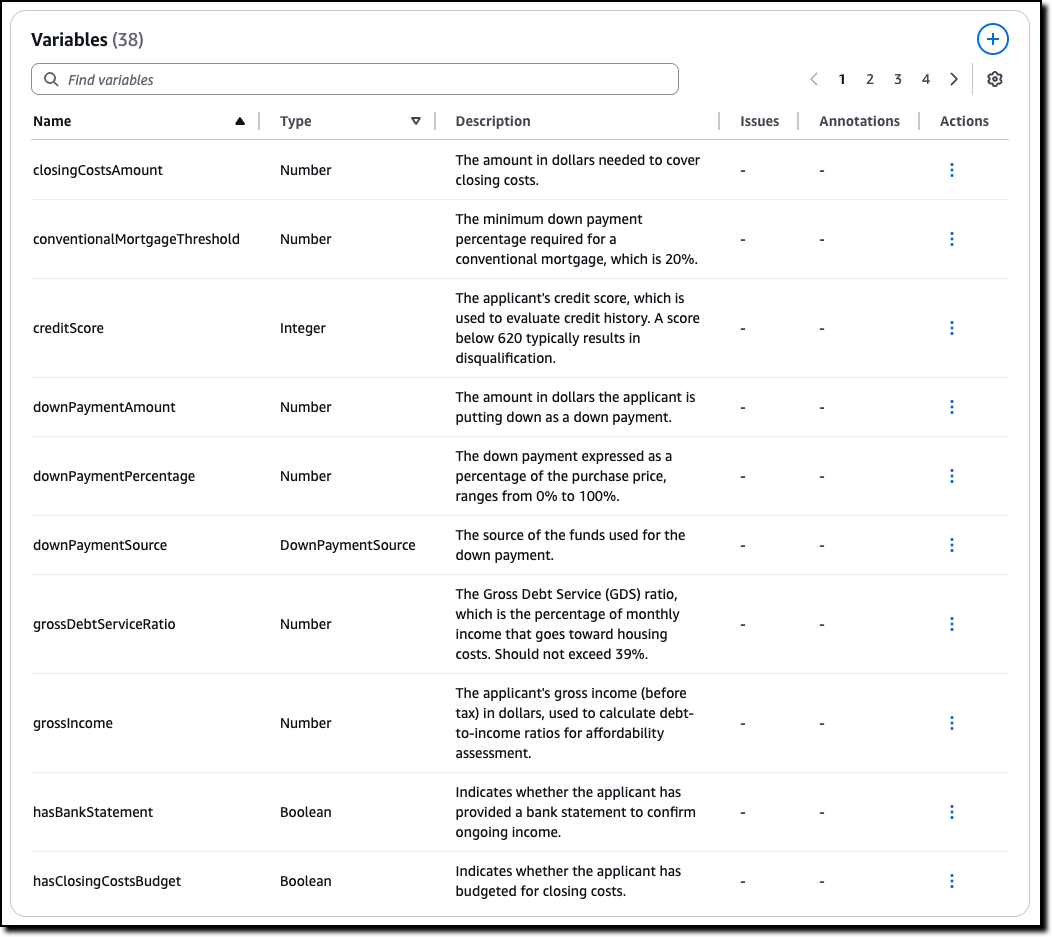
The Variables represent the main concepts at play in the original natural language documents. Each variable is involved in one or more rules. Variables allow complex structures to be easier to understand. For this scenario, some of the rules need to look at the down payment or at the credit score.

Console screenshot.

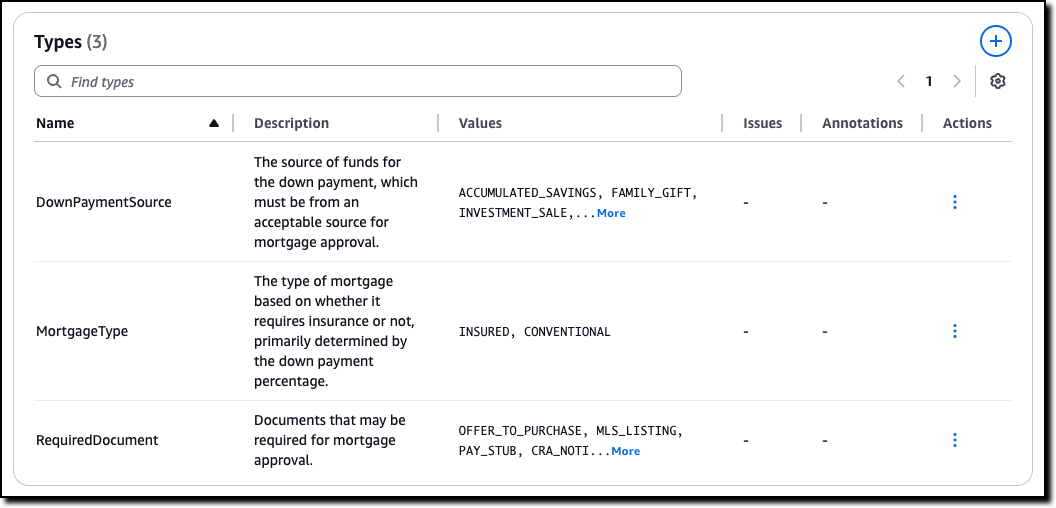
Custom Types are created for variables that are neither boolean nor numeric. For example, for variables that can only assume a limited number of values. In this case, there are two type of mortgage described in the policy, insured and conventional.

Console screenshot.

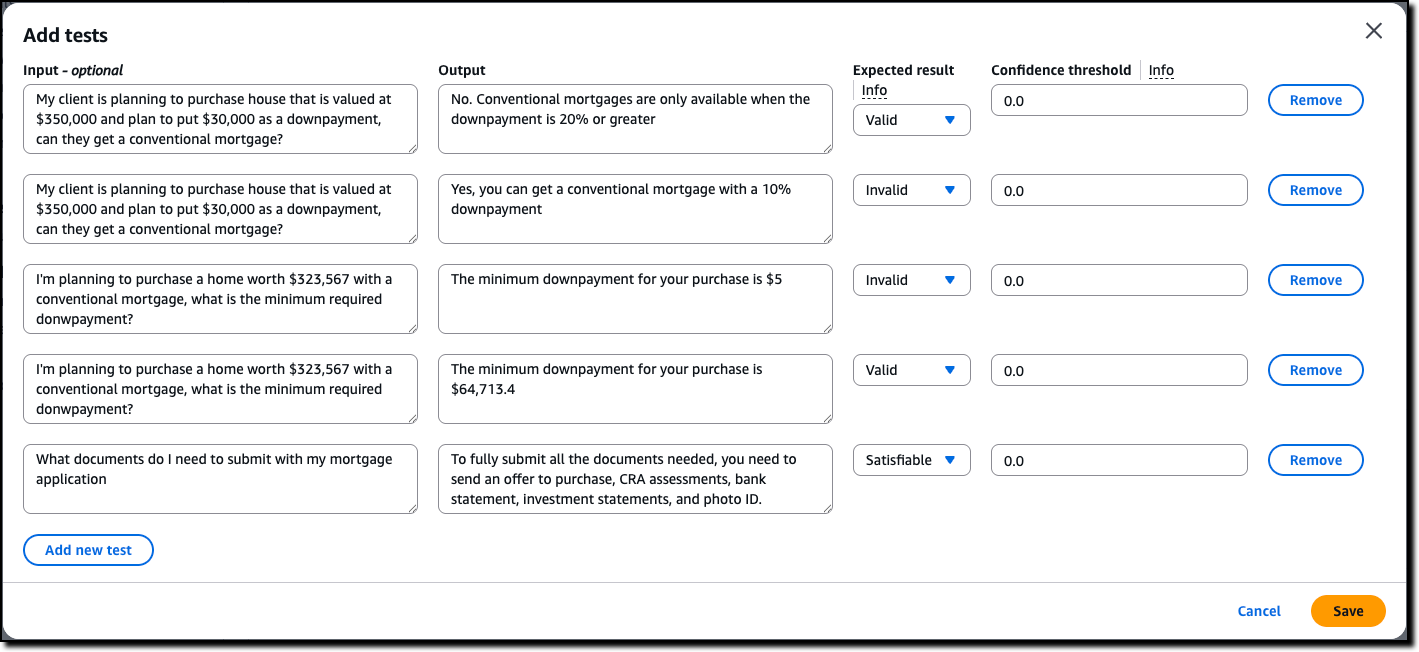
Now we can assess the quality of the initial Automated Reasoning policy through testing. I choose Tests from the dropdown. Here I can manually enter a test, consisting of input (optional) and output, such as a question and its possible answer from the interaction of a customer with the AI assistant. I then set the expected result from the Automated Reasoning check. The expected result can be valid (the answer is correct), invalid (the answer is not correct), or satisfiable (the answer could be true or false depending on specific assumptions). I can also assign a confidence threshold for the translation of the query/content pair from natural language to logic.

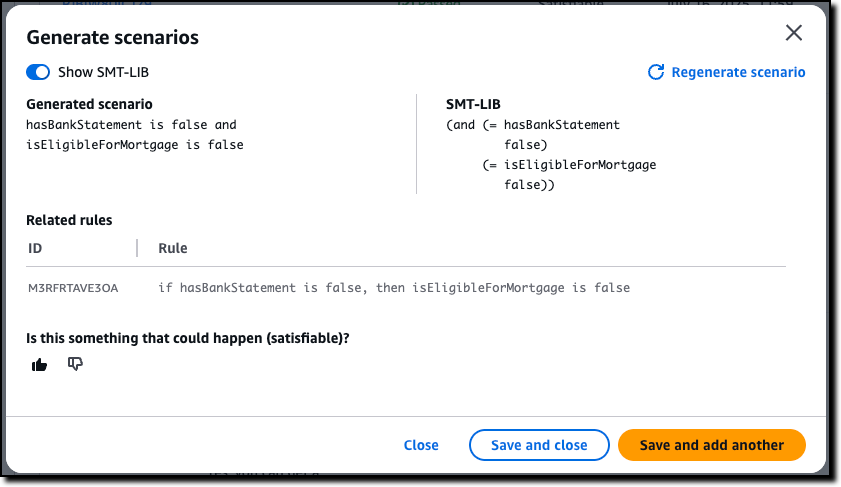
Before I enter tests manually, I use the option to automatically generate a scenario from the definitions. This is the easiest way to validate a policy and (unless you’re an expert in logic) should be the first step after the creation of the policy.

For each generated scenario, I provide an expected validation to say if it is something that can happen (satisfiable) or not (invalid). If not, I can add an annotation that can then be used to update the definitions. For a more advanced understanding of the generated scenario, I can show the formal logic representation of a test using SMT-LIB syntax.

Console screenshot.

After using the generate scenario option, I enter a few tests manually. For these tests, I set different expected results: some are valid, because they follow the policy, some are invalid, because they flout the policy, and some are satisfiable, because their result depends on specific assumptions.

Console screenshot.

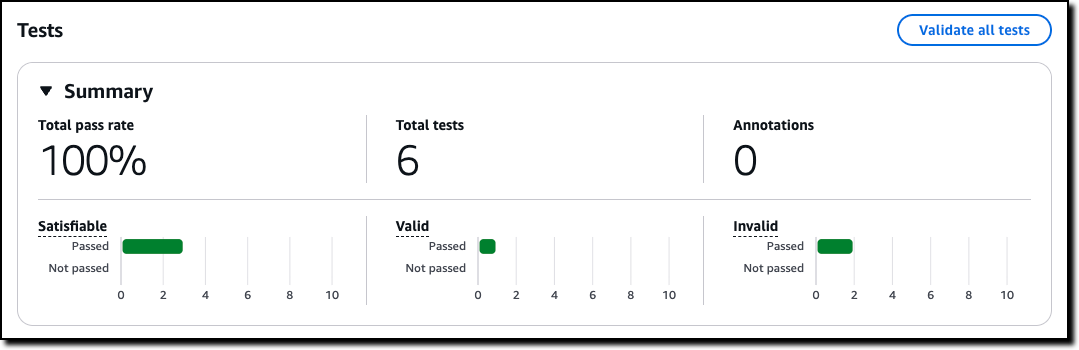
Then, I choose Validate all tests to see the results. All tests passed in this case. Now, when I update the policy, I can use these tests to validate that the changes didn’t introduce errors.

Console screenshot.

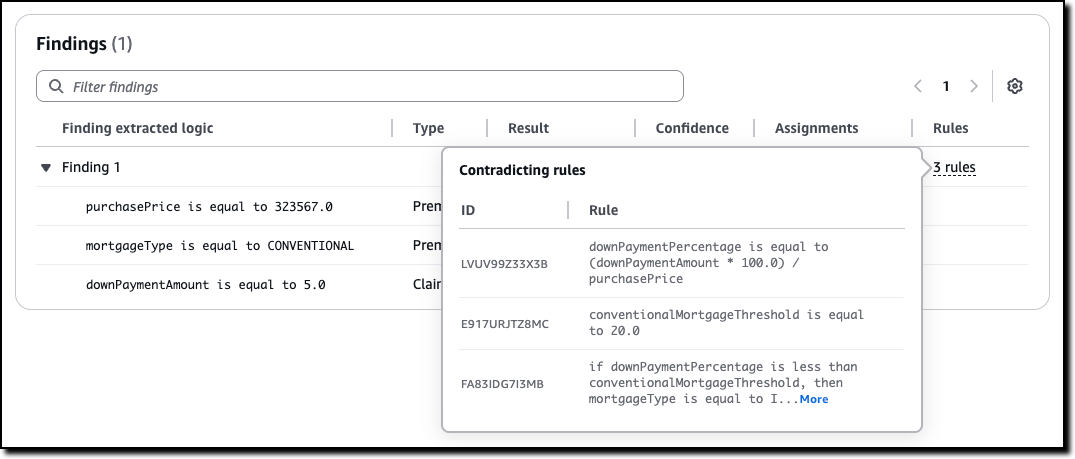
For each test, I can look at the findings. If a test doesn’t pass, I can look at the rules that created the contradiction that made the test fail and go against the expected result. Using this information, I can understand if I should add an annotation, to improve the policy, or correct the test.

Console screenshot.

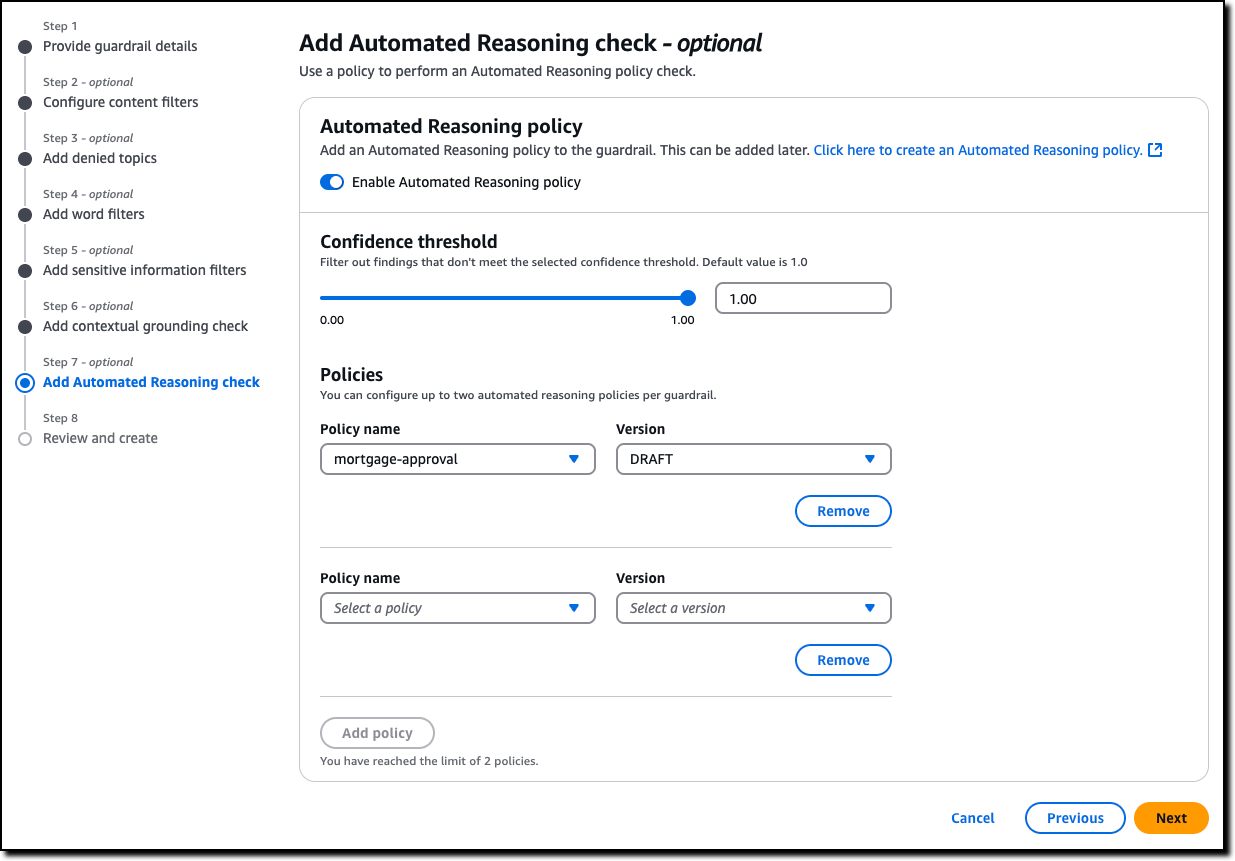
Now that I’m satisfied with the tests, I can create a new Amazon Bedrock guardrail (or update an existing one) to use up to two Automated Reasoning policies to check the validity of the responses of the AI assistant. All six policies offered by Guardrails are modular, and can be used together or separately. For example, Automated Reasoning checks can be used with other safeguards such as content filtering and contextual grounding checks. The guardrail can be applied to models served by Amazon Bedrock or with any third-party model (such as OpenAI and Google Gemini) via the ApplyGuardrail API. I can also use the guardrail with an agent framework such as Strands Agents, including agents deployed using Amazon Bedrock AgentCore.

Console screenshot.

Now that we saw how to set up a policy, let’s look at how Automated Reasoning checks are used in practice.

Customer case study – Utility outage management systems
When the lights go out, every minute counts. That’s why utility companies are turning to AI solutions to improve their outage management systems. We collaborated on a solution in this space together with PwC. Using Automated Reasoning checks, utilities can streamline operations through:

  • Automated protocol generation – Creates standardized procedures that meet regulatory requirements
  • Real-time plan validation – Ensures response plans comply with established policies
  • Structured workflow creation – Develops severity-based workflows with defined response targets

At its core, this solution combines intelligent policy management with optimized response protocols. Automated Reasoning checks are used to assess AI-generated responses. When a response is found to be invalid or satisfiable, the result of the Automated Reasoning check is used to rewrite or enhance the answer.

This approach demonstrates how AI can transform traditional utility operations, making them more efficient, reliable, and responsive to customer needs. By combining mathematical precision with practical requirements, this solution sets a new standard for outage management in the utility sector. The result is faster response times, improved accuracy, and better outcomes for both utilities and their customers.

In the words of Matt Wood, PwC’s Global and US Commercial Technology and Innovation Officer:

“At PwC, we’re helping clients move from AI pilot to production with confidence—especially in highly regulated industries where the cost of a misstep is measured in more than dollars. Our collaboration with AWS on Automated Reasoning checks is a breakthrough in responsible AI: mathematically assessed safeguards, now embedded directly into Amazon Bedrock Guardrails. We’re proud to be AWS’s launch collaborator, bringing this innovation to life across sectors like pharma, utilities, and cloud compliance—where trust isn’t a feature, it’s a requirement.”

Things to know
Automated Reasoning checks in Amazon Bedrock Guardrails is generally available today in the following AWS Regions: US East (Ohio, N. Virginia), US West (Oregon), and Europe (Frankfurt, Ireland, Paris).

With Automated Reasoning checks, you pay based on the amount of text processed. For more information, see Amazon Bedrock pricing.

To learn more, and build secure and safe AI applications, see the technical documentation and the GitHub code samples. Follow this link for direct access to the Amazon Bedrock console.

The videos in this playlist include an introduction to Automated Reasoning checks, a deep dive presentation, and hands-on tutorials to create, test, and refine a policy.

— Danilo

OpenAI open weight models now available on AWS

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/openai-open-weight-models-now-available-on-aws/

AWS is committed to bringing you the most advanced foundation models (FMs) in the industry, continuously expanding our selection to include groundbreaking models from leading AI innovators so that you always have access to the latest advancements to drive your business forward.

Today, I am happy to announce the availability of two new OpenAI models with open weights in Amazon Bedrock and Amazon SageMaker JumpStart. OpenAI gpt-oss-120b and gpt-oss-20b models are designed for text generation and reasoning tasks, offering developers and organizations new options to build AI applications with complete control over their infrastructure and data.

These open weight models excel at coding, scientific analysis, and mathematical reasoning, with performance comparable to leading alternatives. Both models support a 128K context window and provide adjustable reasoning levels (low/medium/high) to match your specific use case requirements. The models support external tools to enhance their capabilities and can be used in an agentic workflow, for example, using a framework like Strands Agents.

With Amazon Bedrock and Amazon SageMaker JumpStart, AWS gives you the freedom to innovate with access to hundreds of FMs from leading AI companies, including OpenAI open weight models. With our comprehensive selection of models, you can match your AI workloads to the perfect model every time.

Through Amazon Bedrock, you can seamlessly experiment with different models, mix and match capabilities, and switch between providers without rewriting code—turning model choice into a strategic advantage that helps you continuously evolve your AI strategy as new innovations emerge. At launch, these new models are available in Bedrock via an OpenAI compatible endpoint. You can point the OpenAI SDK to this endpoint or use the Bedrock InvokeModel and Converse API.

With SageMaker JumpStart, you can quickly evaluate, compare, and customize models for your use case. You can then deploy the original or the customized model in production with the SageMaker AI console or using the SageMaker Python SDK.

Let’s see how these work in practice.

Getting started with OpenAI open weight models in Amazon Bedrock
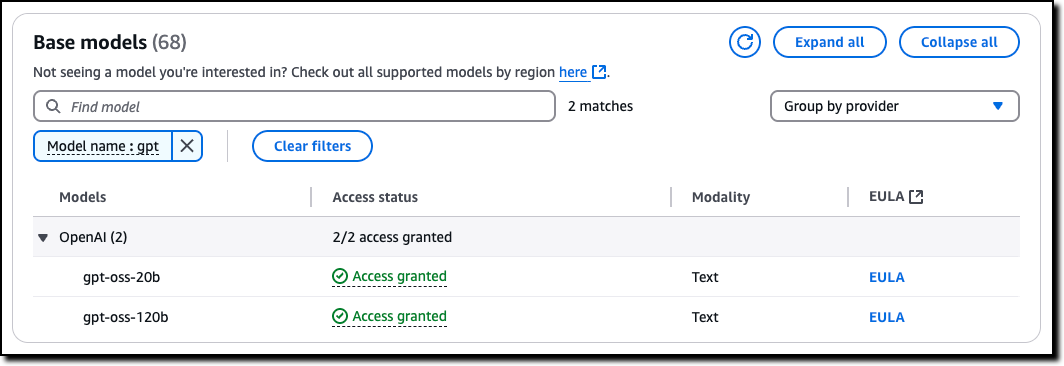
In the Amazon Bedrock console, I choose Model access from the Configure and learn section of the navigation pane. Then, I navigate to the two listed OpenAI models on this page and request access.

Console screenshot

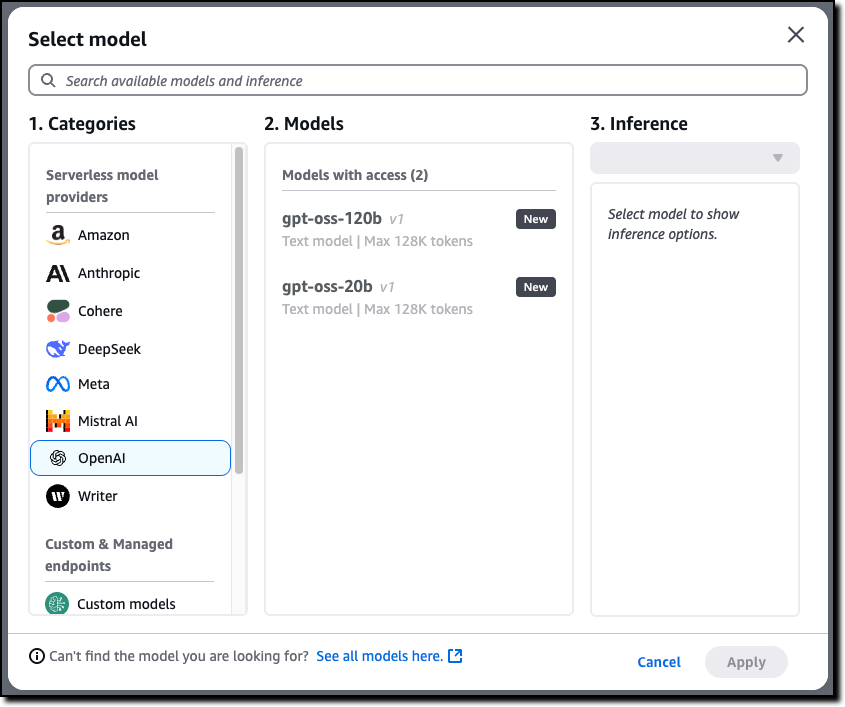
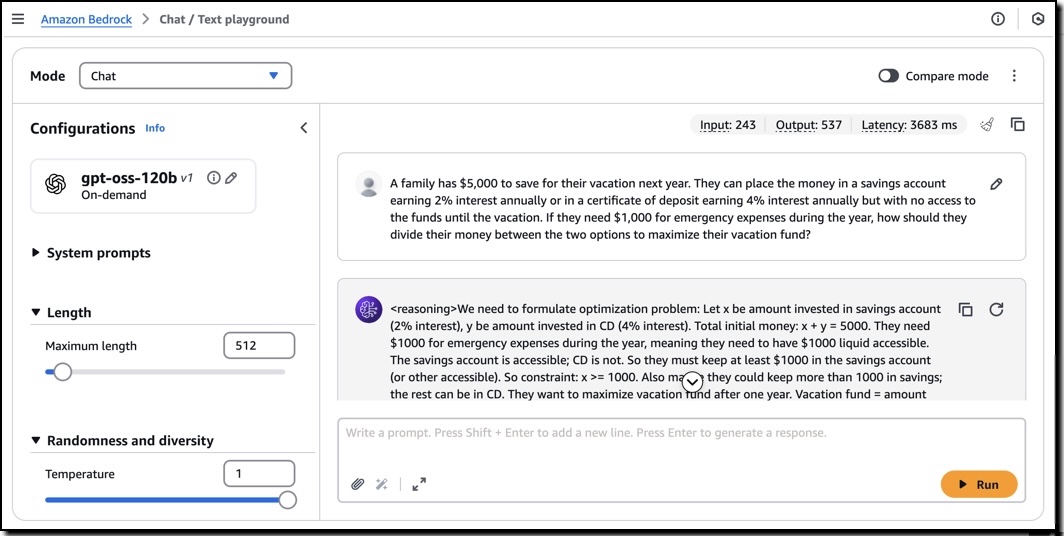
Now that I have access, I use the Chat/Test playground to test and evaluate the models. I select OpenAI as the category and then the gpt-oss-120b model.

Console screenshot

Using this model, I run the following sample prompt:

A family has $5,000 to save for their vacation next year. They can place the money in a savings account earning 2% interest annually or in a certificate of deposit earning 4% interest annually but with no access to the funds until the vacation. If they need $1,000 for emergency expenses during the year, how should they divide their money between the two options to maximize their vacation fund?

This prompt generates an output that includes the chain of thought used to produce the result.

I can use these models with the OpenAI SDK by configuring the API endpoint (base URL) and using an Amazon Bedrock API key for authentication. For example, I set this environment variables to use the US West (Oregon) AWS Region endpoint (us-west-2) and my Amazon Bedrock API key:

export OPENAI_API_KEY="<my-bedrock-api-key>"
export OPENAI_BASE_URL="https://bedrock-runtime.us-west-2.amazonaws.com/openai/v1"

Now I invoke the model using the OpenAI Python SDK.

client = OpenAI()

response = client.chat.completion.create(
    messages=[{
        "role": "user",
        "content": "Hello, how are you?"
    }],
    model="openai.gpt-oss-120b-1:0",
    stream=True
)

for item in response:
    print(item)

To build an AI agent, I can choose any framework that supports the Amazon Bedrock API or the OpenAI API. For example, here’s the starting code for Strands Agents using the Amazon Bedrock API:

from strands import Agent
from strands.models import BedrockModel
from strands_tools import calculator

model = BedrockModel(
    model_id="openai.gpt-oss-120b-1:0"
)
agent = Agent(
    model=model,
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 3")

I save the code (app.py file), install the dependencies, and run the agent locally:

pip install strands-agents strands-agents-tools
python app.py

When I am satisfied with the agent, I can deploy in production using the capabilities offered by Amazon Bedrock AgentCore, including a fully managed serverless runtime and memory and identity management.

Getting started with OpenAI open weight models in Amazon SageMaker JumpStart
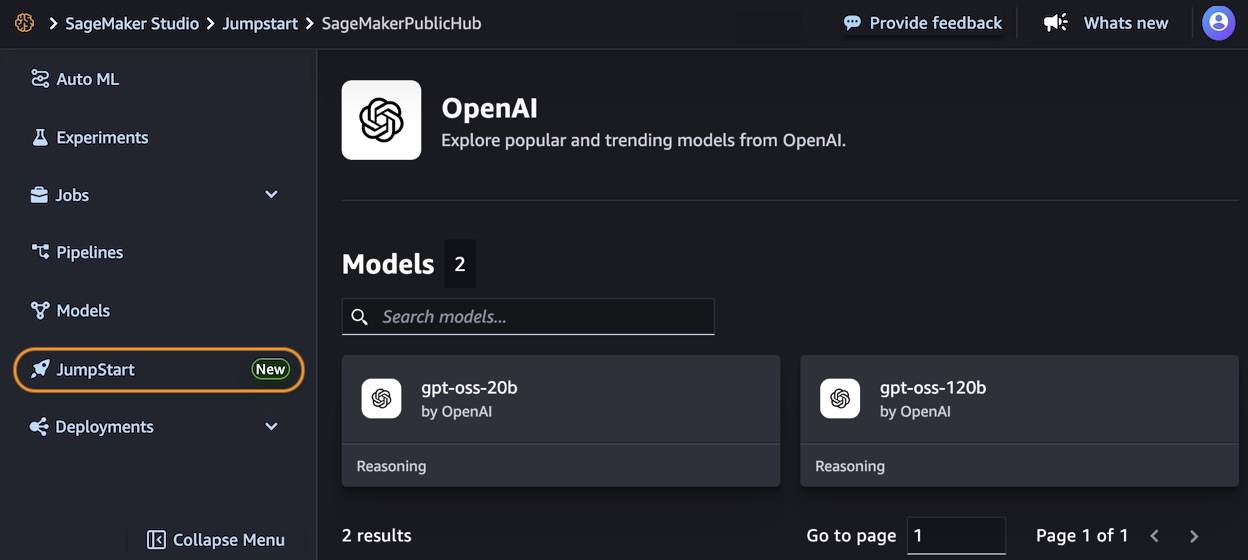
In the Amazon SageMaker AI console, you can use OpenAI open weight models in the SageMaker Studio. The first time I do this, I need to set up a SageMaker domain. There are options to set it up for a single user (simpler) or an organization. For these tests, I use a single user setup.

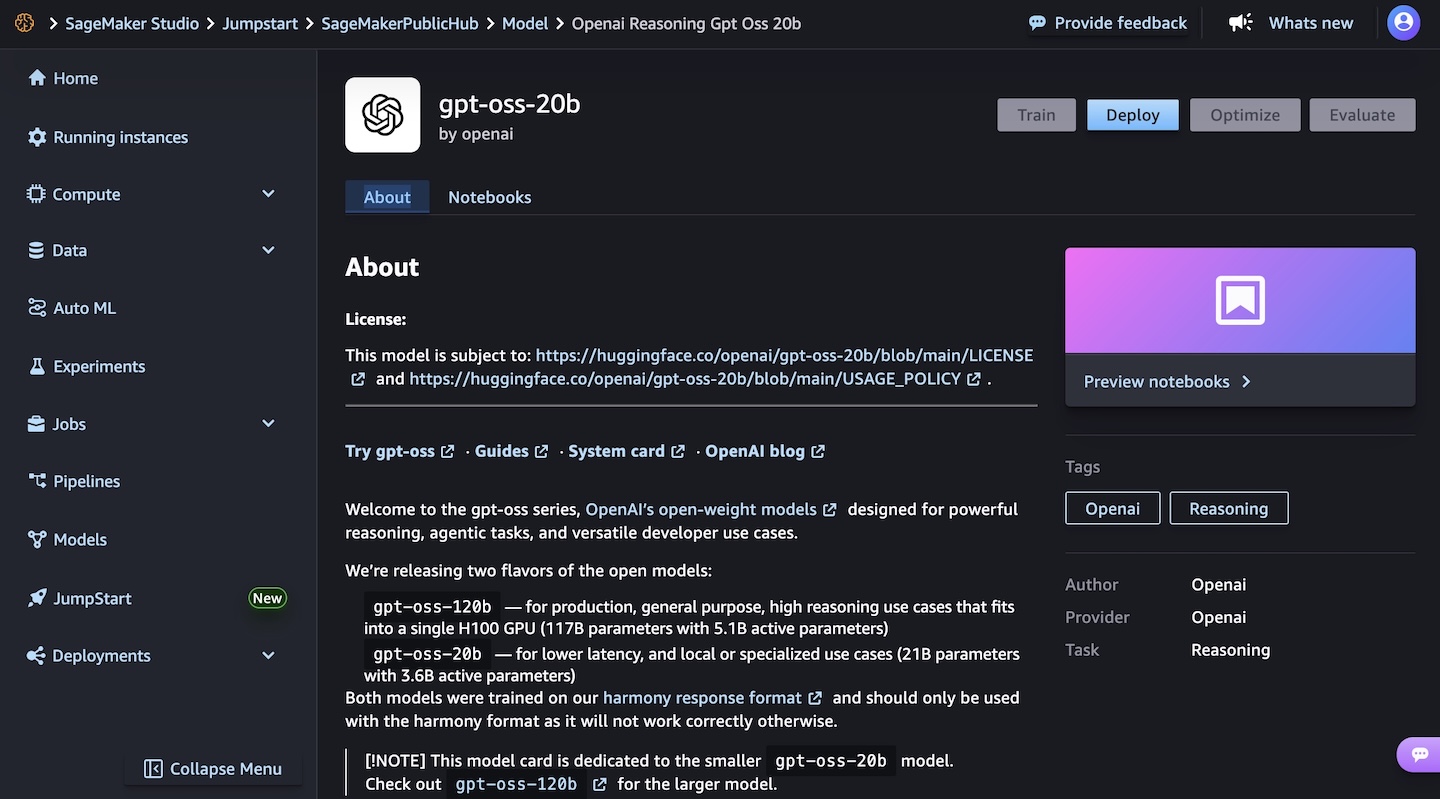
In the SageMaker JumpStart model view, I have access to a detailed description of the gpt-oss-120b or gpt-oss-20b model.

I choose the gpt-oss-20b model and then deploy the model. In the next steps, I select the instance type and the initial instance count. After a few minutes, the deployment creates an endpoint that I can then invoke in SageMaker Studio and using any AWS SDKs.

To learn more, visit GPT OSS models from OpenAI are now available on SageMaker JumpStart in the AWS Artificial Intelligence Blog.

Things to know
The new OpenAI open weight models are now available in Amazon Bedrock in the US West (Oregon) AWS Region, while Amazon SageMaker JumpStart supports these models in US East (Ohio, N. Virginia) and Asia Pacific (Mumbai, Tokyo).

Each model comes equipped with full chain-of-thought output capabilities, providing you with detailed visibility into the model’s reasoning process. This transparency is particularly valuable for applications requiring high levels of interpretability and validation. These models give you the freedom to modify, adapt, and customize them to your specific needs. This flexibility allows you to fine-tune the models for your unique use cases, integrate them into your existing workflows, and even build upon them to create new, specialized models tailored to your industry or application.

Security and safety are built into the core of these models, with comprehensive evaluation processes and safety measures in place. The models maintain compatibility with the standard GPT-4 tokenizer.

Both models can be used in your preferred environment, whether that’s through the serverless experience of Amazon Bedrock or the extensive machine learning (ML) development capabilities of SageMaker JumpStart. For information about the costs associated with using these models and services, visit the Amazon Bedrock pricing and Amazon SageMaker AI pricing pages.

To learn more, see the parameters for the models and the chat completions API in the Amazon Bedrock documentation.

Get started today with OpenAI open weight models on AWS in the Amazon Bedrock console or in Amazon SageMaker AI console.

– Danilo

Accelerating development with the AWS Data Processing MCP Server and Agent

Post Syndicated from Shubham Mehta original https://aws.amazon.com/blogs/big-data/accelerating-development-with-the-aws-data-processing-mcp-server-and-agent/

Data engineering teams face an increasingly complex landscape when building and maintaining analytics environments. From sourcing and organizing data to implementing transformation pipelines and managing access controls, the process of transforming raw data into actionable insights involves numerous interconnected components. While individual tools exist for each task, connecting them into cohesive workflows remains time-consuming and requires deep technical expertise across multiple AWS services.

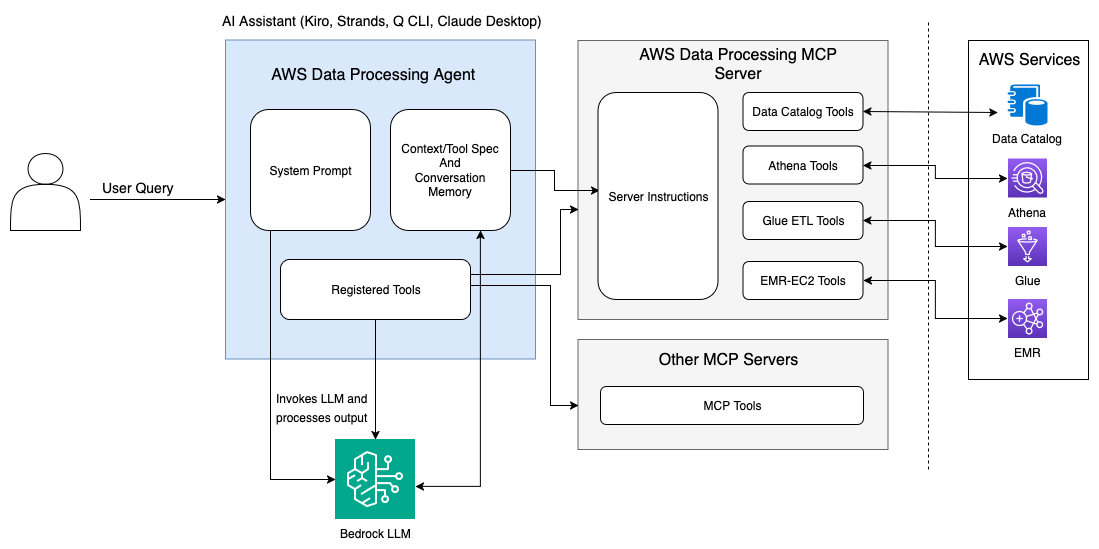
To address these challenges and enhance developer productivity, we’re excited to introduce the AWS Data Processing MCP Server, an open-source tool that uses the Model Context Protocol (MCP) to simplify analytics environment setup on AWS. We’re also open sourcing a stand-alone Data Processing Agent implementation in AWS Strands SDK to use this MCP server to help customers further customize it for their use cases. This powerful integration enables AI assistants to understand your data processing environment and guide you through complex workflows using natural language interactions.

Understanding the Model Context Protocol advantage

The MCP is an emerging open standard that defines how AI models, particularly large language models (LLMs), can securely access and interact with external tools, data sources, and services. Rather than requiring developers to learn intricate API syntax across multiple services, MCP enables AI assistants to understand your environment contextually and provide intelligent guidance throughout your data processing journey.

The AWS Data Processing MCP Server harnesses this capability by providing AI code assistants with real-time visibility into your AWS data processing pipeline. This includes access to AWS Glue job statuses, Amazon Athena query results, Amazon EMR cluster metrics, and AWS Glue Data Catalog metadata through a unified interface that LLMs can understand and reason about.

AWS analytics integration

The AWS Data Processing MCP Server integrates deeply with AWS Glue for data cataloging and ETL operations, Amazon EMR for big data processing, and Athena for serverless analytics. This integration transforms how developers interact with these services by providing contextual awareness that enables AI assistants and Data Processing Strands Agent to make intelligent recommendations based on your actual infrastructure and data patterns.

Rather than requiring manual navigation between service consoles or memorizing complex API parameters, the MCP server enables natural language interactions that automatically translate to appropriate service operations. This approach reduces the learning curve for new team members while accelerating productivity for experienced developers working across multiple AWS analytics services.

Getting started with the AWS Data Processing MCP Server

You’ll need to follow the steps in the prerequisites section before you can start using MCP servers.

Prerequisites

Before configuring the MCP server, ensure you have the following prerequisites in place:

System requirements:

  • macOS or supported Linux environment
  • Python 3.10 or higher
  • UV package manager for Python dependency management
  • AWS Command Line Interface (AWS CLI) installed and configured with appropriate credentials

IAM permissions: Review and configure your security policies for the IAM roles and permissions that would grant necessary access to the AWS Data Processing MCP Server and Agent to execute AWS data processing operations on your behalf. For read-only operations, attach policies that include permissions for Data Catalog access, Amazon CloudWatch metrics, Amazon EMR cluster descriptions, and Athena query operations. For write operations, make sure that your AWS Identity and Access Management (IAM) role includes the AWSGlueServiceRole managed policy along with permissions for creating and managing Amazon EMR clusters and Athena workgroups.

Set up using Amazon Q CLI

Amazon Q Developer CLI provides an intuitive way to interact with the AWS Data Processing MCP Server directly from your terminal. This integration combines the natural language processing capabilities of Amazon Q with the data processing tools, enabling you to manage complex analytics workflows through conversational commands.

Installation and configuration:

  1. Install the Amazon Q Developer CLI.
  2. Clone the MCP Server repository:

git clone https://github.com/awslabs/mcp

  1. Edit your Q Developer CLI’s MCP configuration file named mcp.json:
{
  "mcpServers": {
    "aws.dp-mcp": {
      "autoApprove": [],
      "disabled": false,
      "command": "uvx",
      "args": [
        "awslabs.aws-dataprocessing-mcp-server@latest",
        "--allow-write"
      ],
      "env": {
        "AWS_PROFILE": "your-aws-profile",
        "AWS_REGION": "your-preferred-region"
      }
    }
  }
}
  1. Verify your setup by running the /tools command in the Q Developer CLI to see the available Data Processing MCP tools.

Set up using Claude Desktop

Claude Desktop offers another powerful way to interact with the AWS Data Processing MCP Server through Anthropic’s Claude interface, providing a user-friendly chat experience for managing your data processing workflows.

Installation and configuration:

  1. Download and install Claude Desktop for your operating system.
  2. Open Claude Desktop and navigate to Settings (gear icon in the bottom left).
  3. Go to the Developer tab and configure your MCP server by adding same configuration as step 3 in Q CLI setup.
  4. Restart Claude Desktop to activate the MCP server connection.
  5. Test the integration by starting a new conversation and asking: What data processing tools are available to me?

Enhanced developer experience

After being configured with either Amazon Q CLI or Claude Desktop, your workflow transforms dramatically. Instead of constructing complex AWS CLI commands with multiple parameters, you can use natural language requests. For example, rather than memorizing the syntax for creating AWS Glue crawlers, you can ask:

Create a Glue crawler for my S3 bucket that runs weekly and updates the data catalog with any schema changes

Accelerating development with MCP servers

Next, we explore the common patterns that emerge when using MCP in data processing development workflows.

Data onboarding and discovery

One of the most common challenges data teams face is efficiently onboarding new datasets and making them immediately useful for analysis. Consider a scenario where your marketing team receives a CSV file containing customer interaction data that needs to be quickly analyzed for campaign insights. Traditionally, this process involves multiple manual steps: uploading the file to Amazon Simple Storage Service (Amazon S3), configuring an AWS Glue crawler to discover the schema, creating appropriate table definitions, setting up proper partitioning, and finally making the data queriable through Athena.

With the AWS Data Processing MCP Server, this entire workflow becomes conversational. You can describe your goal using natural language:

I have a customer interaction CSV file that I need to analyze for marketing insights. Help me get this data ready for business users to query

The AI assistant, powered by the MCP server’s deep AWS integration, automatically handles the technical implementation details, guides you through uploading the file to an appropriate Amazon S3 location, configures and runs an AWS Glue crawler with optimal settings, creates properly formatted table definitions, and sets up Athena access with appropriate workgroup configurations for cost control.

The following video demonstration showcases how developers can use Amazon Q CLI with Data Processing MCP server for data onboarding.

Business insights and automated reporting

Modern organizations require timely, accurate insights to drive business decisions, but traditional analytics workflows often create bottlenecks between data availability and business consumption. Imagine you need to identify potentially fraudulent transactions across multiple data sources including cardholder information, credit card details, merchant data, and transaction records. Rather than manually writing complex SQL queries with multiple joins and filters, you can describe your analytical goal:

Analyze our transaction data across cardholders, credit cards, and merchants to identify suspicious activities involving transactions over $5,000 and create an automated weekly report.

The MCP server interprets this request and automatically constructs the appropriate analytical workflow. It examines your data catalog to understand table relationships, generates optimized SQL queries with proper joins across your datasets, executes the analysis using Athena with cost-effective query patterns, and formats the results into actionable reports. The system can establish automated delivery mechanisms, such as email reports or dashboard updates, ensuring stakeholders receive timely insights without manual intervention while creating scheduled AWS Glue jobs that continuously monitor for emerging patterns.

We’re also releasing a stand-alone Data Processing Agent developed using AWS Strands SDK that you can customize further with your system prompts and context for your use cases. You can run it locally or deploy it using Amazon Bedrock AgentCore. The following video demonstration showcases how developers can use Data Processing Agent for driving business insights.

Observability and performance monitoring

Maintaining visibility across complex data processing environments requires sophisticated monitoring capabilities that traditional approaches often fail to provide. The AWS Data Processing MCP Server enables intelligent observability by synthesizing real-time telemetry from across your AWS analytics infrastructure into actionable insights. For AWS Glue environments, the MCP server continuously analyzes job metadata, execution logs, resource configurations, and data catalog statistics to provide operational intelligence. Rather than manually navigating CloudWatch dashboards or parsing log files, you can ask questions like Show me performance trends across my ETL jobs and identify optimization opportunities. The following video demonstration showcases how developers can use Claude Desktop with Data Processing MCP Server to monitor Glue jobs and catalogs.

For Amazon EMR clusters, the MCP server aggregates cluster metadata, instance usage patterns, and failure events into unified operational views. This enables proactive management where you can request Analyze my EMR environment for cost optimization opportunities and potential reliability risks. The system responds with detailed analysis of cluster utilization patterns, recommendations for right-sizing instance types, identification of long-running clusters that might represent cost leakage, and alerts about configuration patterns that could impact reliability. The observability capabilities extend beyond simple monitoring to predictive insights by analyzing historical patterns to forecasting resource needs and recommend preventive actions. The following video demonstration showcases how developers can use Claude Desktop with Data Processing MCP Server to monitor EMR clusters.

Security and architectural considerations

All MCP server operations occur within your AWS account boundaries, helping to ensure that sensitive data does not leave your controlled environment. The server provides contextual information to AI assistants through metadata and API responses based on IAM access permissions available to the role being used. Integration with IAM helps ensure that operations respect existing permission boundaries and organizational policies.

The architecture supports graduated autonomy where routine operations can proceed automatically while high-impact changes require human approval. This balanced approach enables productivity gains while maintaining appropriate oversight for critical business operations.

Conclusion

In this post, we explored how the AWS Data Processing MCP Server accelerates analytics solution development across our analytics services. We demonstrated how data engineers can transform raw data into business-ready insights through AI-assisted workflows, significantly reducing development time and complexity. The AWS Data Processing MCP Server offers extensive capabilities beyond these use cases. You can use the MCP’s context-rich APIs to develop customized solutions for observability, automation, and optimization. This flexibility allows you to create workflows tailored to your specific data environments and business needs.By bringing AWS data processing capabilities directly into development workflows—whether through AWS CLI, IDEs, or AI-assisted tools—teams can focus on solving business problems rather than managing infrastructure. We encourage you to explore innovative applications of the MCP Server, combining its powerful context engine with AI-driven analysis to uncover new opportunities for efficiency and insight across their data ecosystems.

Get started today by accessing the open source code, documentation, and setup instructions in the AWS Labs GitHub repository. Integrate the MCP Server into your development workflow and transform how you build analytics solutions on AWS. We’ll continue to iterate based on customer feedback and look forward to seeing how customers extend these capabilities to solve complex data challenges.

Acknowledgment: A special thanks to everyone who contributed to the development and open-sourcing of the AWS Data Processing MCP server and Agent: Raghavendhar Thiruvoipadi Vidyasagar, Chris Kha, Sandeep Adwankar, Nidhi Gupta, Xiaoxi Liu, Kathryn Lin, Alexa Perlov, Alain Krok, Xiaorun Yu, Maheedhar Reddy Chapiddi, and Rajendra Gujja. 


About the authors

Shubham Mehta is a Senior Product Manager at AWS Analytics. He leads generative AI feature development across services such as AWS Glue, Amazon EMR, and Amazon MWAA, using AI/ML to simplify and enhance the experience of data practitioners building data applications on AWS.

Vaibhav Naik is a software engineer at AWS Glue, passionate about building robust, scalable solutions to tackle complex customer problems. With a keen interest in generative AI, he likes to explore innovative ways to develop enterprise-level solutions that harness the power of cutting-edge AI technologies.

Liyuan Lin is a Software Engineer at AWS Glue, where she works on building generative AI and data integration tools to help customers solve their data challenges. She specializes in developing solutions that combine AI capabilities with data integration workflows, making it easier for customers to manage and transform their data effectively.

Arun A K is a Big Data Solutions Architect with AWS. He works with customers to provide architectural guidance for running analytics solutions on the cloud. In his free time, Arun loves to enjoy quality time with his family.

Sarath Krishnan is a Senior Solutions Architect with Amazon Web Services. He is passionate about enabling enterprise customers on their digital transformation journey. Sarath has extensive experience in architecting highly available, scalable, cost-effective, and resilient applications on the cloud. His area of focus includes DevOps, machine learning, MLOps, and generative AI.

Pradeep Patel is a Software Development Manager on the AWS Data Processing Team (AWS Glue and Amazon EMR). His team focuses on building distributed systems to enable seamless Spark Code Transformation using AI.

Mohit Saxena is a Senior Software Development Manager on the AWS Data Processing Team (AWS Glue and Amazon EMR). His team focuses on building distributed systems to enable customers with new AI/ML-driven capabilities to efficiently transform petabytes of data across data lakes on Amazon S3, databases and data warehouses on the cloud.

Optimizing vector search using Amazon S3 Vectors and Amazon OpenSearch Service

Post Syndicated from Sohaib Katariwala original https://aws.amazon.com/blogs/big-data/optimizing-vector-search-using-amazon-s3-vectors-and-amazon-opensearch-service/

NOTE: As of July 15, the Amazon S3 Vectors Integration with Amazon OpenSearch Service is in preview release and is subject to change.

The way we store and search through data is evolving rapidly with the advancement of vector embeddings and similarity search capabilities. Vector search has become essential for modern applications such as generative AI and agentic AI, but managing vector data at scale presents significant challenges. Organizations often struggle with the trade-offs between latency, cost, and accuracy when storing and searching through millions or billions of vector embeddings. Traditional solutions either require substantial infrastructure management or come with prohibitive costs as data volumes grow.

We now have a public preview of two integrations between Amazon Simple Storage Service (Amazon S3) Vectors and Amazon OpenSearch Service that give you more flexibility in how you store and search vector embeddings:

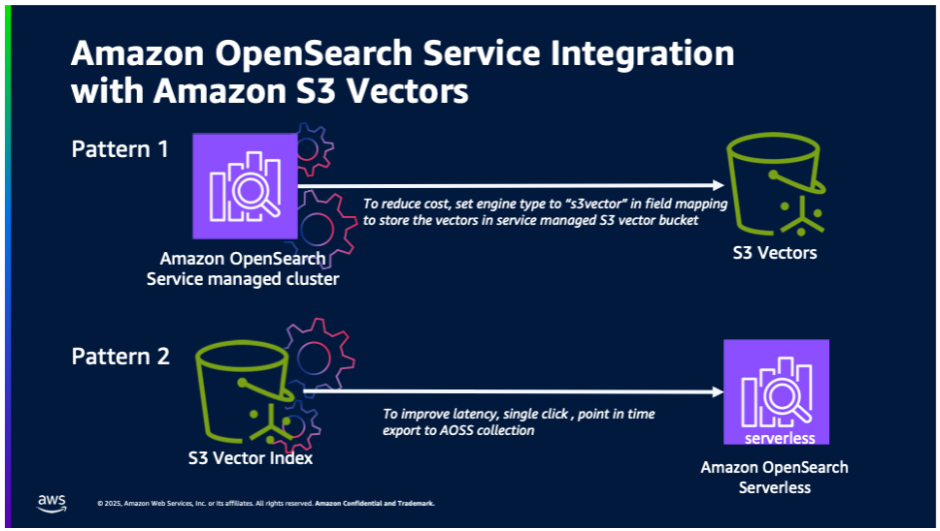
  1. Cost-optimized vector storage: OpenSearch Service managed clusters using service-managed S3 Vectors for cost-optimized vector storage. This integration will support OpenSearch workloads that are willing to trade off higher latency for ultra-low cost and still want to use advanced OpenSearch capabilities (such as hybrid search, advanced filtering, geo filtering, and so on).
  2. One-click export from S3 Vectors: One-click export from an S3 vector index to OpenSearch Serverless collections for high-performance vector search. Customers who build natively on S3 Vectors will benefit from being able to use OpenSearch for faster query performance.

By using these integrations, you can optimize cost, latency, and accuracy by intelligently distributing your vector workloads by keeping infrequent queried vectors in S3 Vectors and using OpenSearch for your most time-sensitive operations that require advanced search capabilities such as hybrid search and aggregations. Further, OpenSearch performance tuning capabilities (that is, quantization, k-nearest neighbor (knn) algorithms, and method-specific parameters) help to improve the performance with little compromise of cost or accuracy.

In this post, we walk through this seamless integration, providing you with flexible options for vector search implementation. You’ll learn how to use the new S3 Vectors engine type in OpenSearch Service managed clusters for cost-optimized vector storage and how to use one-click export from S3 Vectors to OpenSearch Serverless collections for high-performance scenarios requiring sustained queries with latency as low as 10ms. By the end of this post, you’ll understand how to choose and implement the right integration pattern based on your specific requirements for performance, cost, and scale.

Service overview

Amazon S3 Vectors is the first cloud object store with native support to store and query vectors with sub-second search capabilities, requiring no infrastructure management. It combines the simplicity, durability, availability, and cost-effectiveness of Amazon S3 with native vector search functionality, so you can store and query vector embeddings directly in S3. Amazon OpenSearch Service provides two complementary deployment options for vector workloads: Managed Clusters and Serverless Collections. Both harness Amazon OpenSearch’s powerful vector search and retrieval capabilities, though each excels in different scenarios. For OpenSearch users, the integration between S3 Vectors and Amazon OpenSearch Service offers unprecedented flexibility in optimizing your vector search architecture. Whether you need ultra-fast query performance for real-time applications or cost-effective storage for large-scale vector datasets, this integration lets you choose the approach that best fits your specific use case.

Understanding Vector Storage Options

OpenSearch Service provides multiple options for storing and searching vector embeddings, each optimized for different use cases. The Lucene engine, which is OpenSearch’s native search library, implements the Hierarchical Navigable Small World (HNSW) method, offering efficient filtering capabilities and strong integration with OpenSearch’s core functionality. For workloads requiring additional optimization options, the Faiss engine (Facebook AI Similarity Search) provides implementations of both HNSW and IVF (Inverted File Index) methods, along with vector compression capabilities. HNSW creates a hierarchical graph structure of connections between vectors, enabling efficient navigation during search, while IVF organizes vectors into clusters and searches only relevant subsets during query time. With the introduction of the S3 engine type, you now have a cost-effective option that uses Amazon S3’s durability and scalability while maintaining sub-second query performance. With this variety of options, you can choose the most suitable approach based on your specific requirements for performance, cost, and accuracy. For instance, if your application requires sub-50 ms query responses with efficient filtering, Faiss’s HNSW implementation is the best choice. Alternatively, if you need to optimize storage costs while maintaining reasonable performance, the new S3 engine type would be more appropriate.

Solution overview

In this post, we explore two primary integration patterns:

OpenSearch Service managed clusters using service-managed S3 Vectors for cost-optimized vector storage.

For customers already using OpenSearch Service domains who want to optimize costs while maintaining sub-second query performance, the new Amazon S3 engine type offers a compelling solution. OpenSearch Service automatically manages vector storage in Amazon S3, data retrieval, and cache optimization, eliminating operational overhead.

One-click export from an S3 vector index to OpenSearch Serverless collections for high-performance vector search.

For use cases requiring faster query performance, you can migrate your vector data from an S3 vector index to an OpenSearch Serverless collection. This approach is ideal for applications that require real-time response times and gives you the benefits that come with Amazon OpenSearch Serverless, including advanced query capabilities and filters, automatic scaling and high availability, and no administration. The export process automatically handles schema mapping, vector data transfer, index optimization, and connection configuration.

The following illustration shows the two integration patterns between Amazon OpenSearch Service and S3 Vectors.

Prerequisites

Before you begin, make sure you have:

  • An AWS account
  • Access to Amazon S3 and Amazon OpenSearch Service
  • An OpenSearch Service domain (for the first integration pattern)
  • Vector data stored in S3 Vectors (for the second integration pattern)

Integration pattern 1: OpenSearch Service managed cluster using S3 Vectors

To implement this pattern:

  1. Create an OpenSearch Service Domain using OR1 instances on OpenSearch version 2.19.
    1. While creating the OpenSearch Service domain, choose the Enable S3 Vectors as an engine option in the Advanced features section.
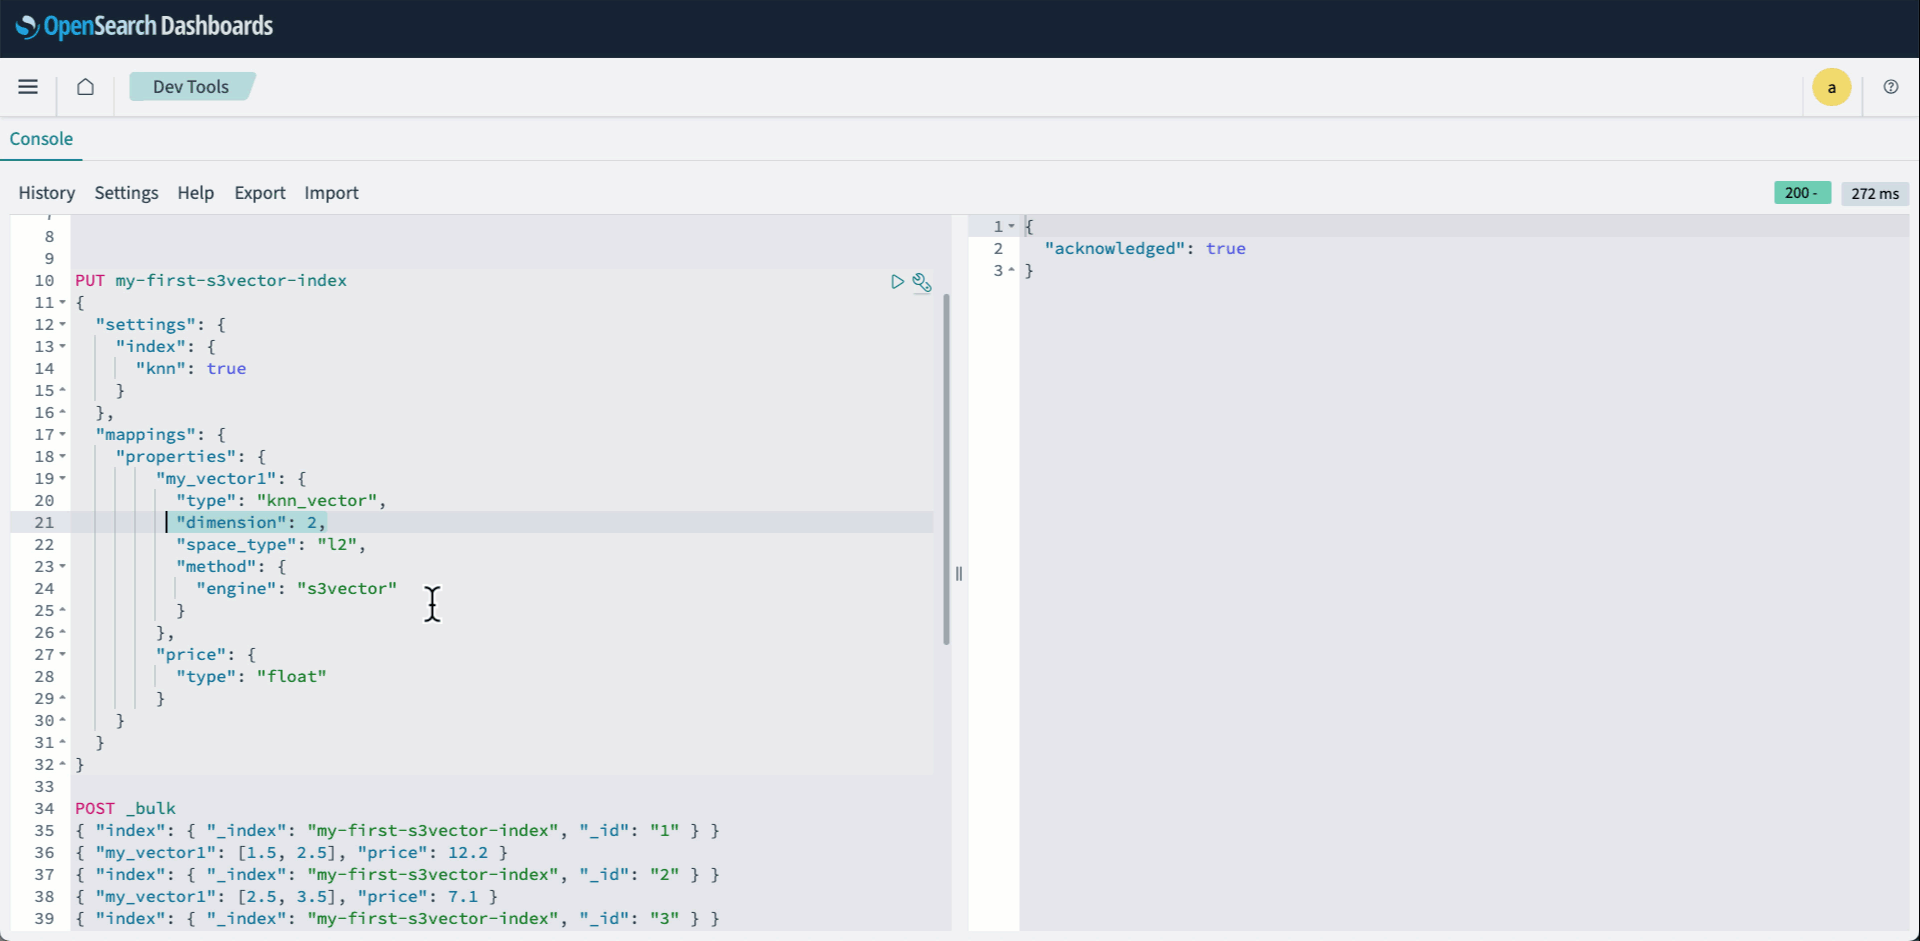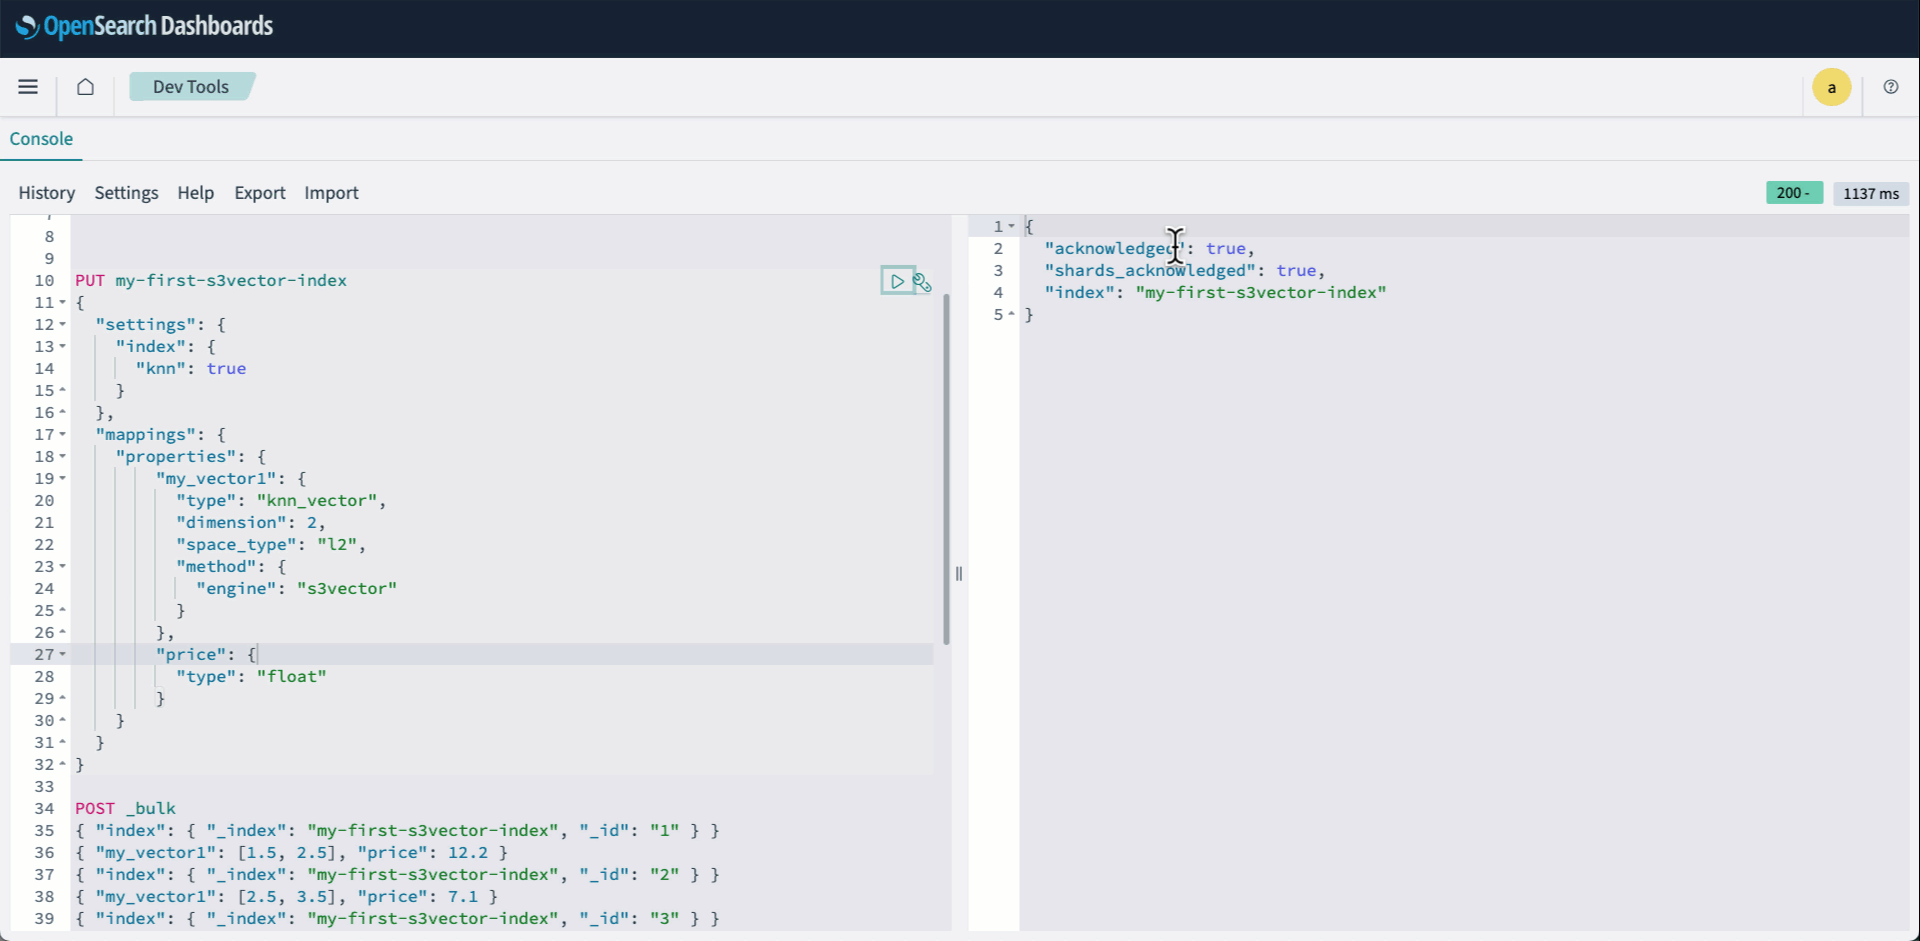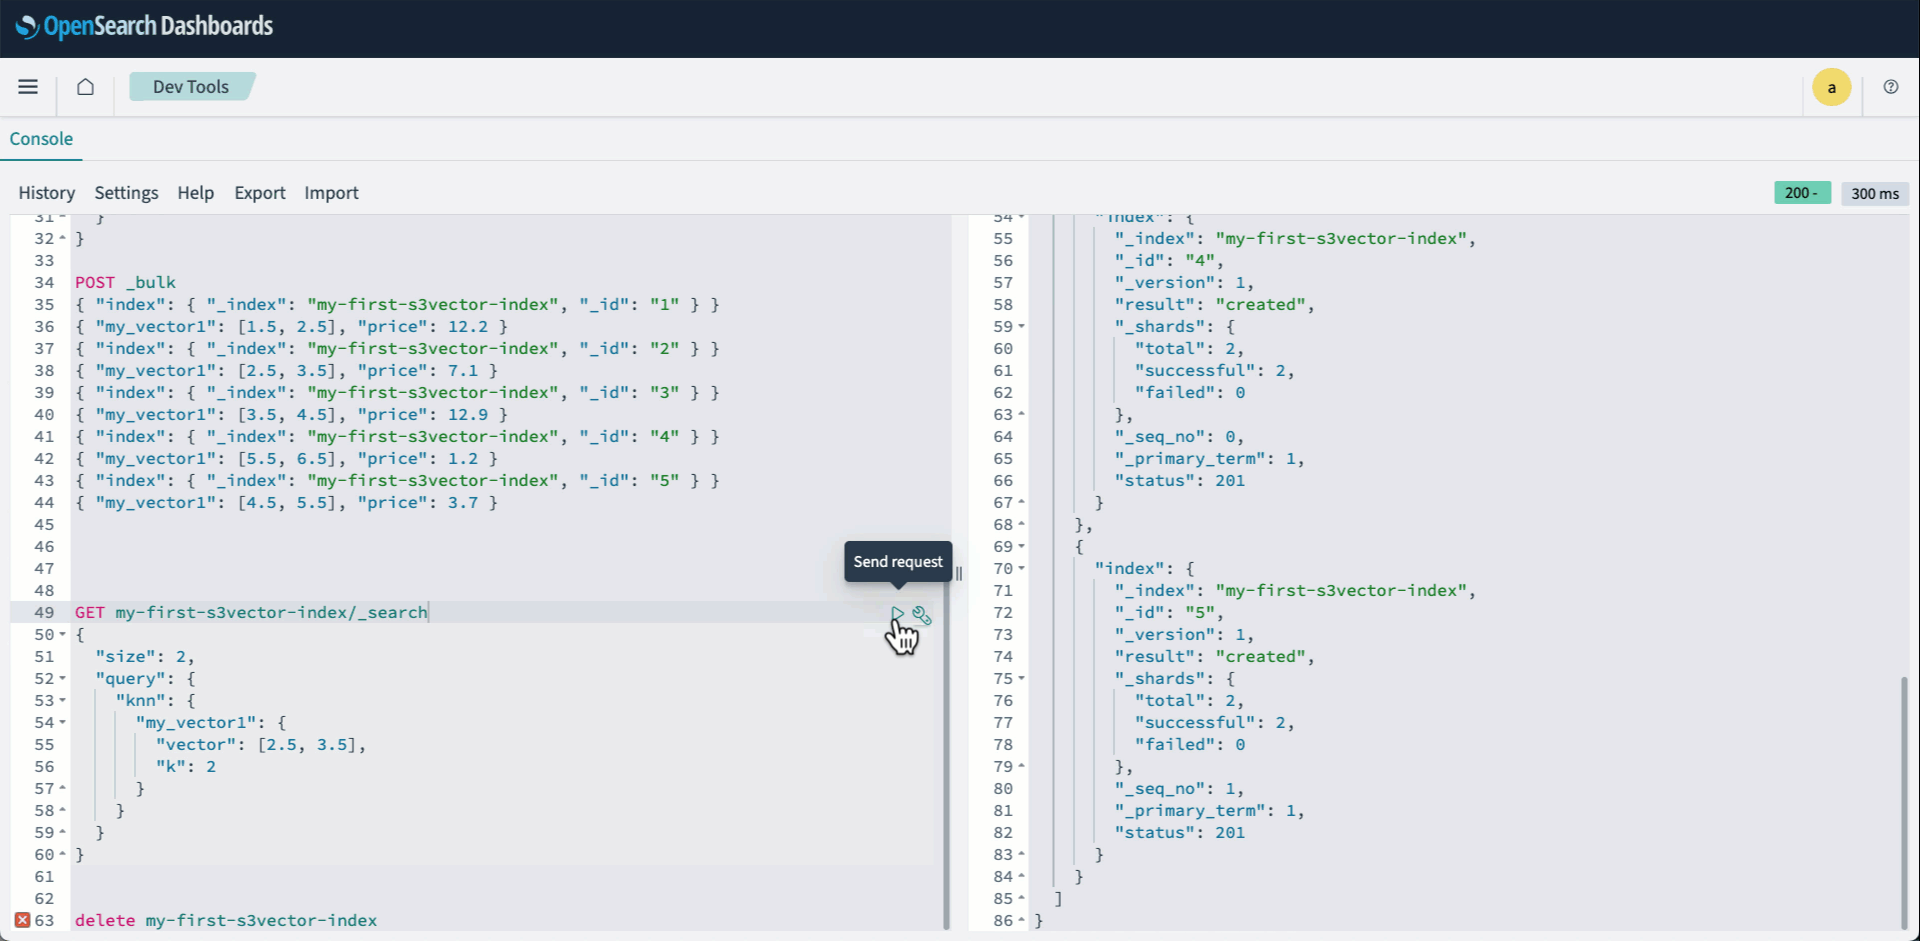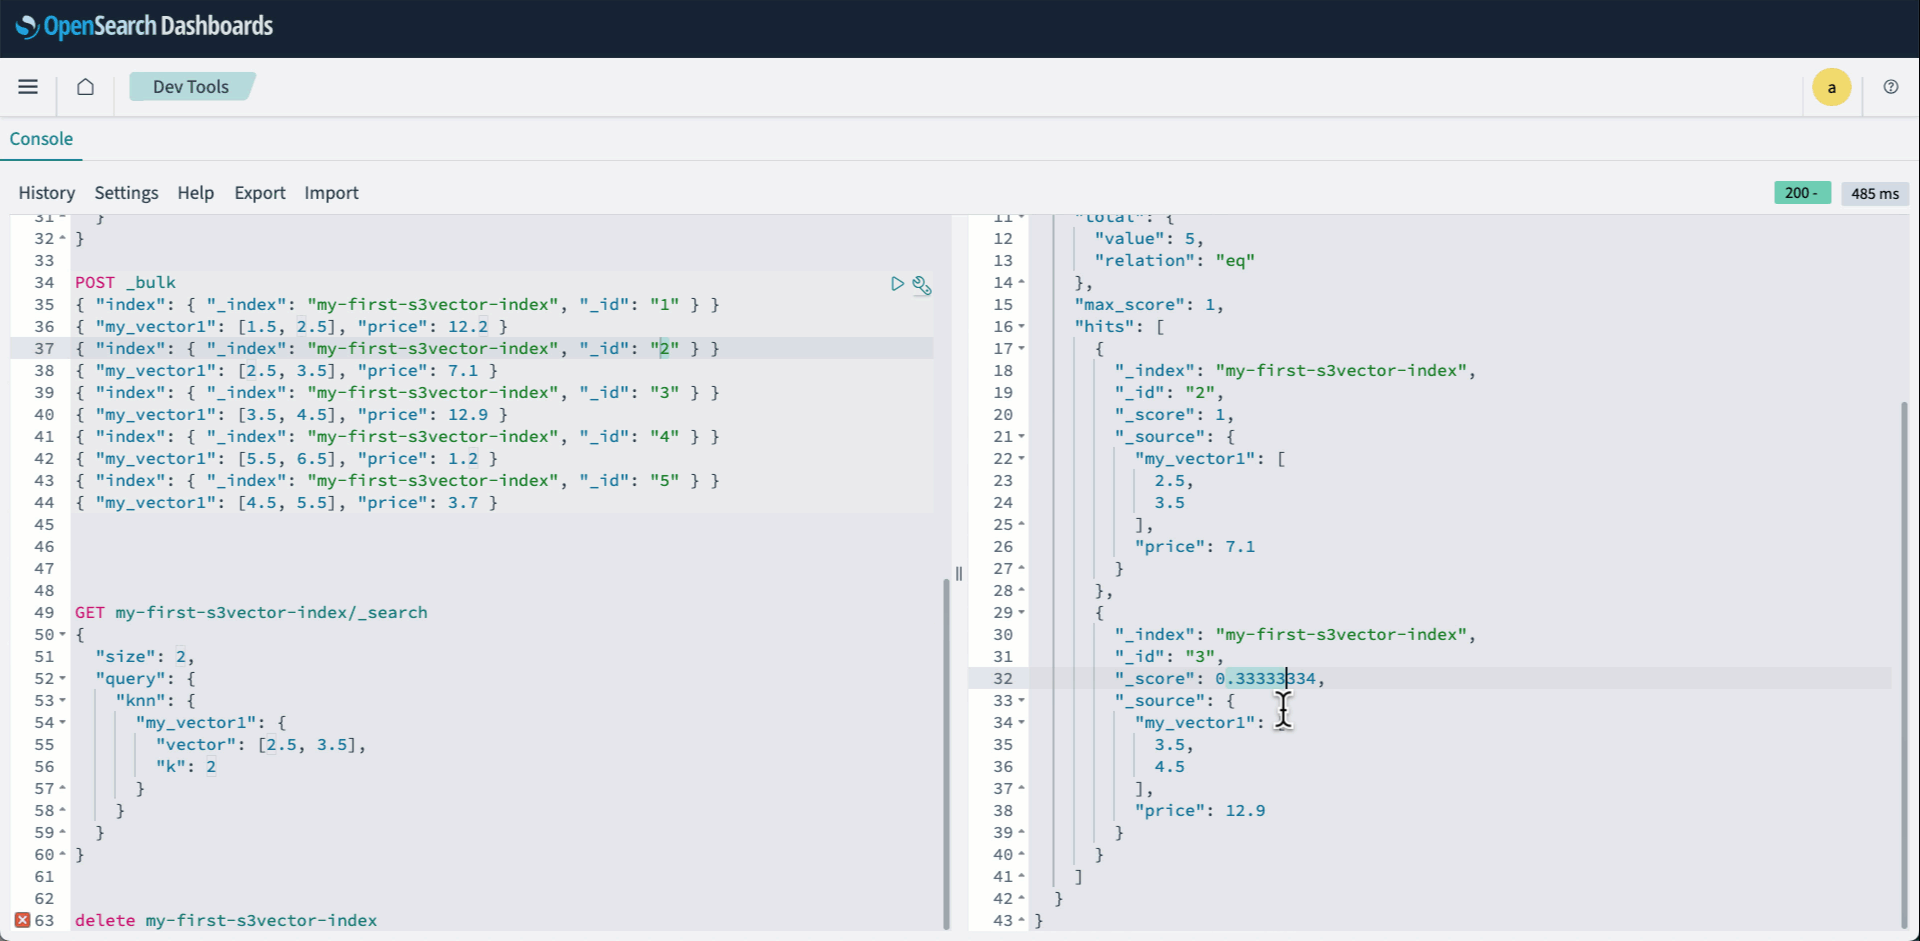
  2. Sign in to OpenSearch Dashboards and open Dev tools. Then create your knn index and specify s3vector as the engine.
PUT my-first-s3vector-index
{
  "settings": {
    "index": {
      "knn": true
    }
  },
  "mappings": {
    "properties": {
        "my_vector1": {
          "type": "knn_vector",
          "dimension": 2,
          "space_type": "l2",
          "method": {
            "engine": "s3vector"
          }
        },
        "price": {
          "type": "float"
        }
    }
  }
} 
  1. Index your vectors using the Bulk API:
POST _bulk
{ "index": { "_index": "my-first-s3vector-index", "_id": "1" } }
{ "my_vector1": [2.5, 3.5], "price": 7.1 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "3" } }
{ "my_vector1": [3.5, 4.5], "price": 12.9 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "4" } }
{ "my_vector1": [5.5, 6.5], "price": 1.2 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "5" } }
{ "my_vector1": [4.5, 5.5], "price": 3.7 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "6" } }
{ "my_vector1": [1.5, 2.5], "price": 12.2 }
  1. Run a knn query as usual:
GET my-first-s3vector-index/_search
{
  "size": 2,
  "query": {
    "knn": {
      "my_vector1": {
        "vector": [2.5, 3.5],
        "k": 2
      }
    }
  }
}

The following animation demonstrates steps 2-4 above.

Integration pattern 2: Export S3 vector indexes to OpenSearch Serverless

To implement this pattern:

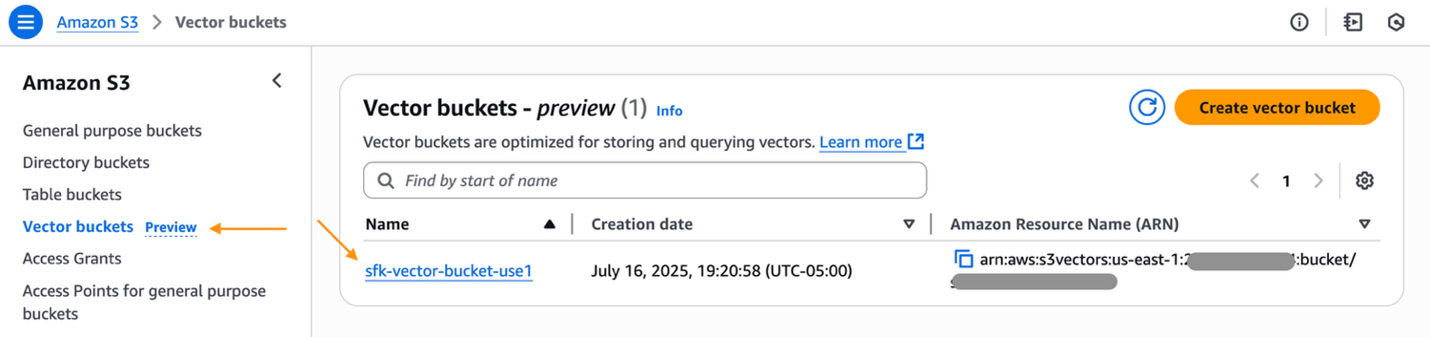
  1. Navigate to the AWS Management Console for Amazon S3 and select your S3 vector bucket.

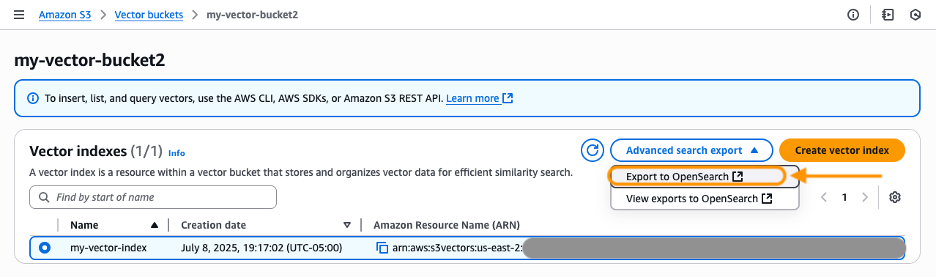
  1. Select a vector index that you want to export. Under Advanced search export, select Export to OpenSearch.

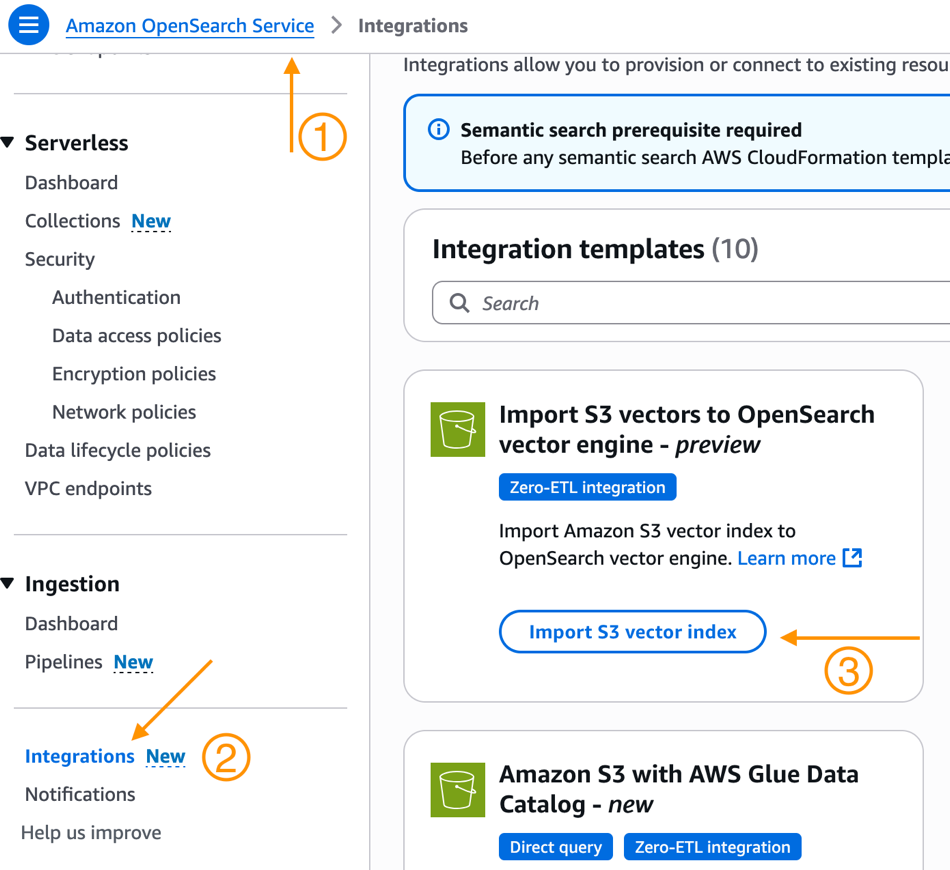
Alternatively, you can:

  1. Navigate to the OpenSearch Service console.
  2. Select Integrations from the navigation pane.
  3. Here you will see a new Integration Template to Import S3 vectors to OpenSearch vector engine – preview. Select Import S3 vector index.

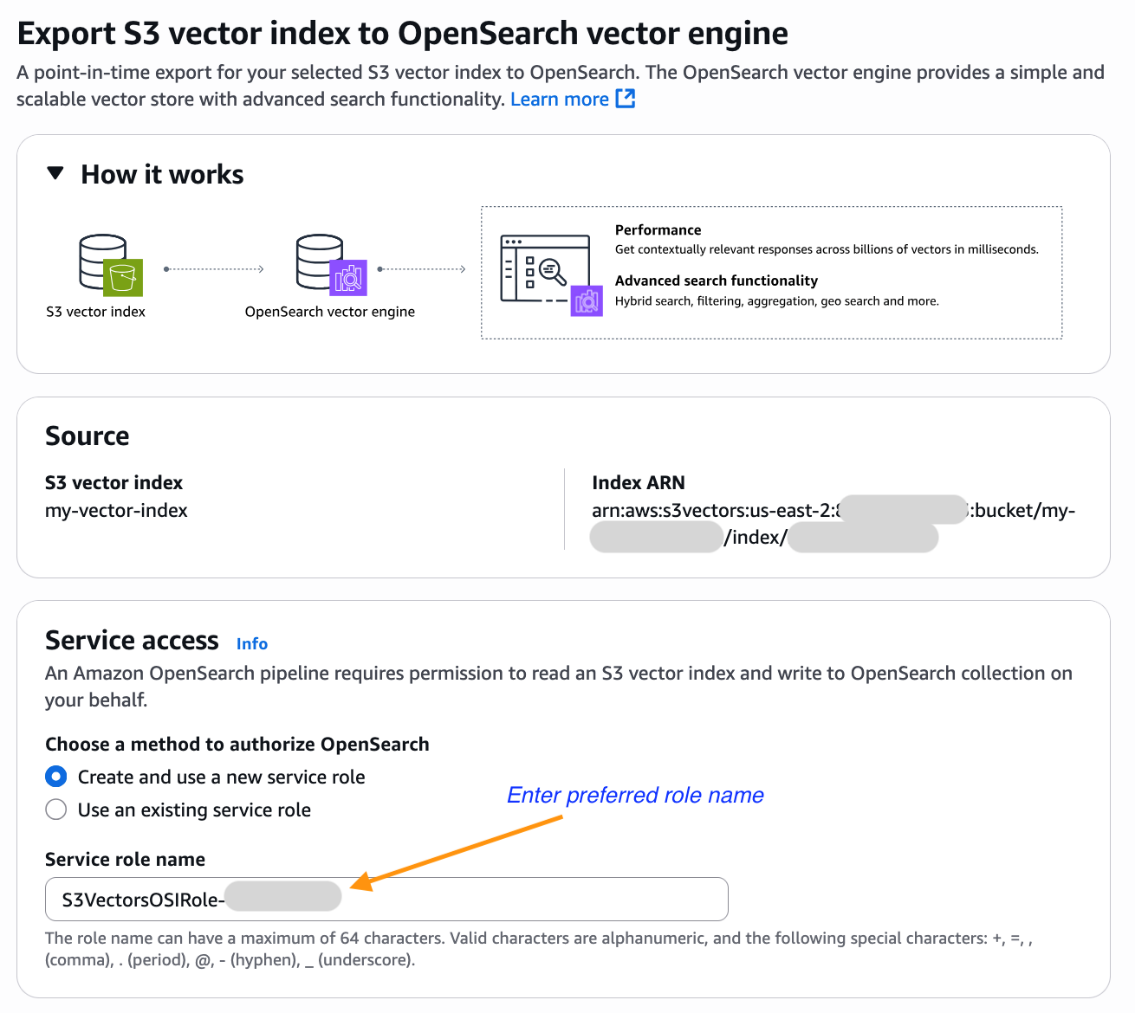
  1. You will now be brought to the Amazon OpenSearch Service integration console with the Export S3 vector index to OpenSearch vector engine template pre-selected and pre-populated with your S3 vector index Amazon Resource Name (ARN). Select an existing role that has the necessary permissions or create a new service role.

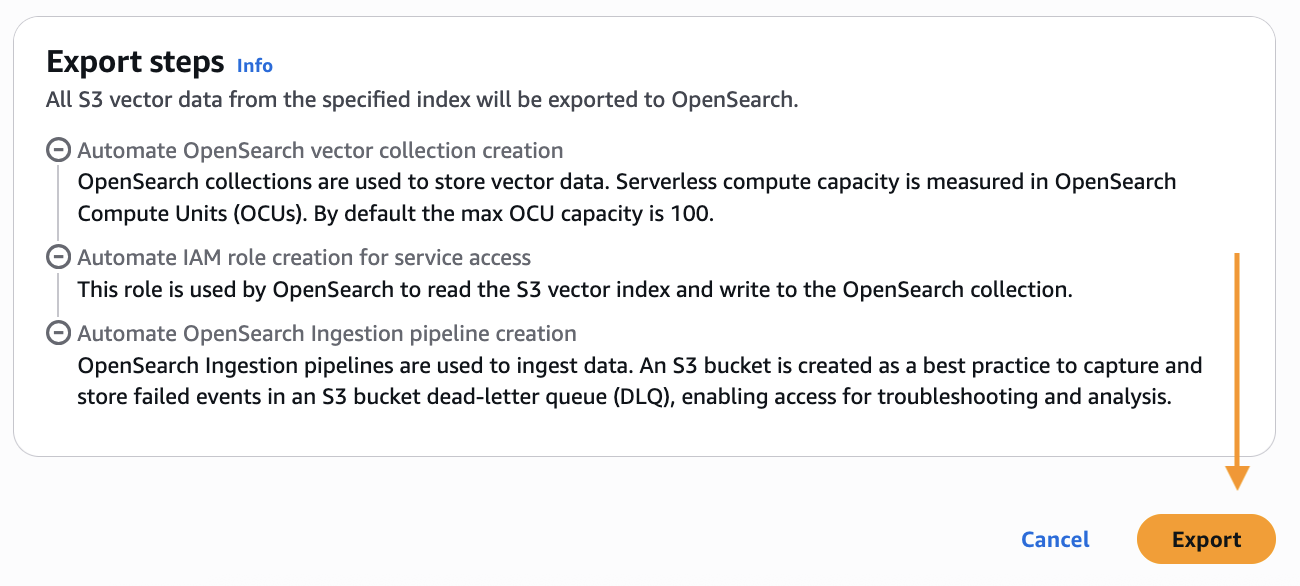
  1. Scroll down and choose Export to start the steps to create a new OpenSearch Serverless collection and copy data from your S3 vector index into an OpenSearch knn index.

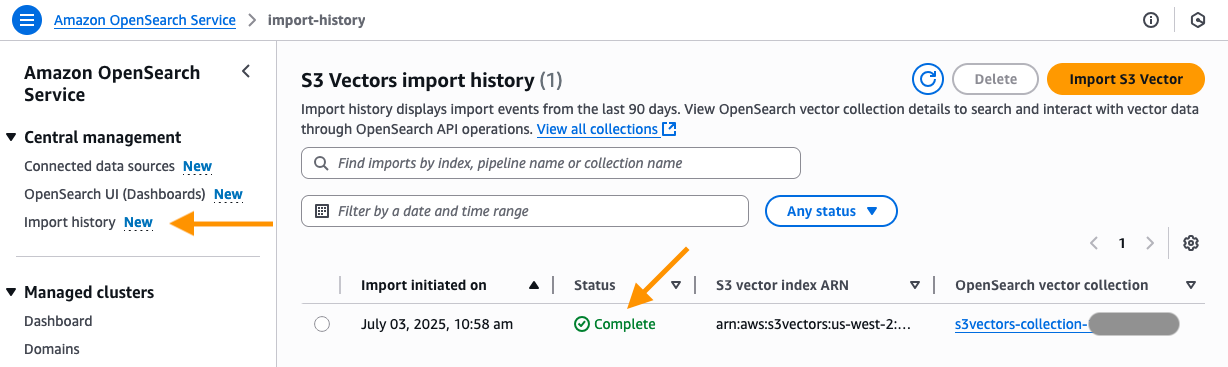
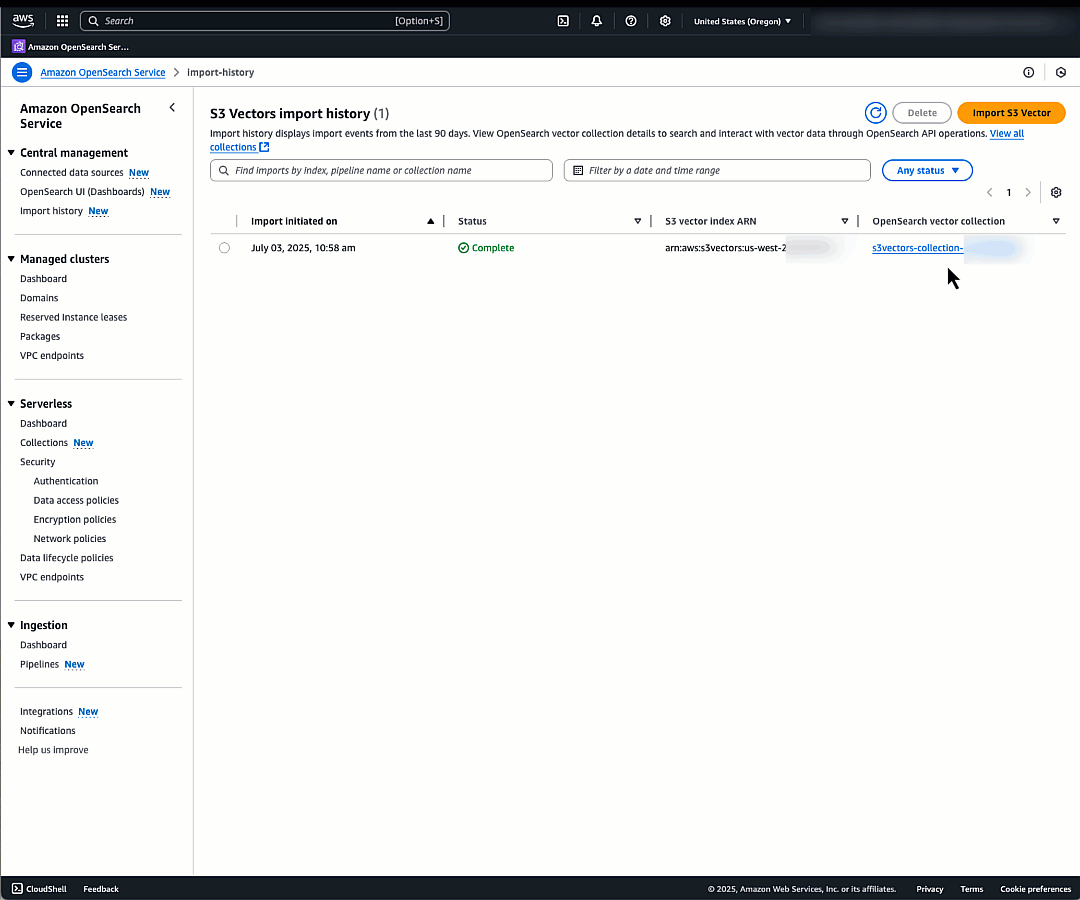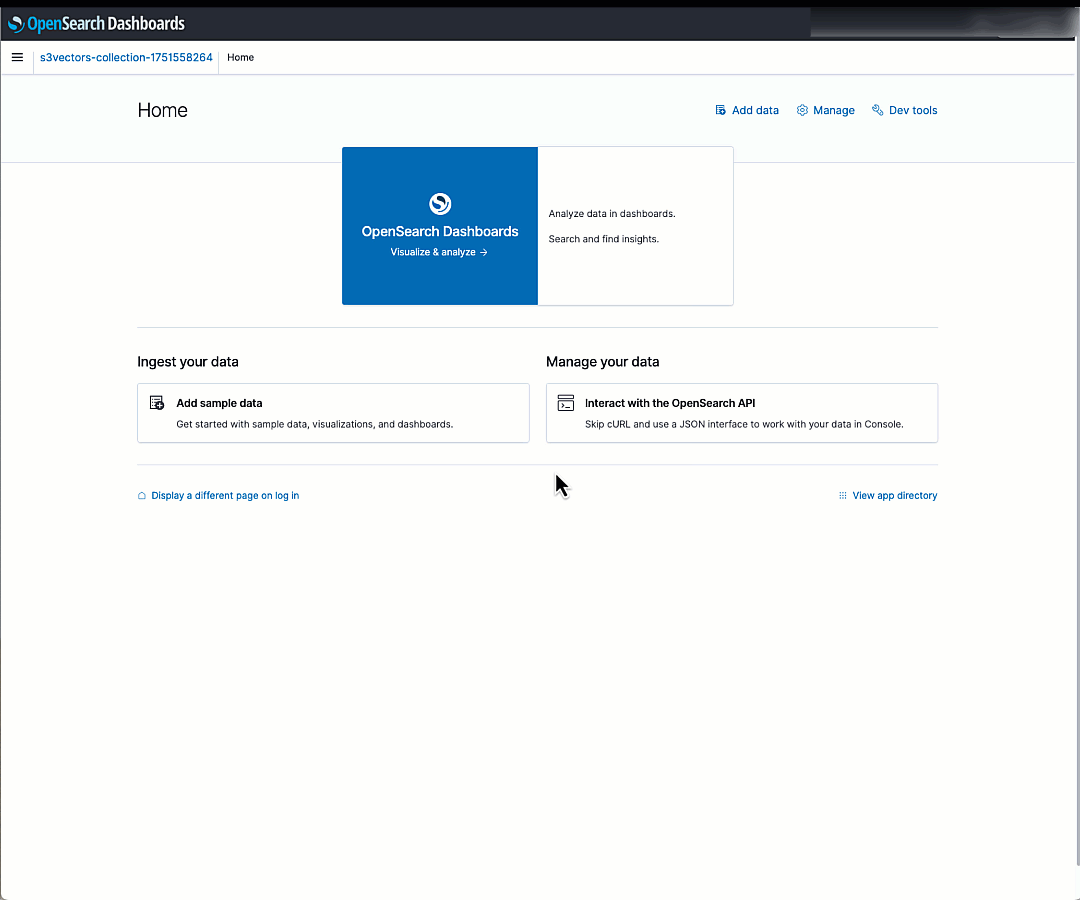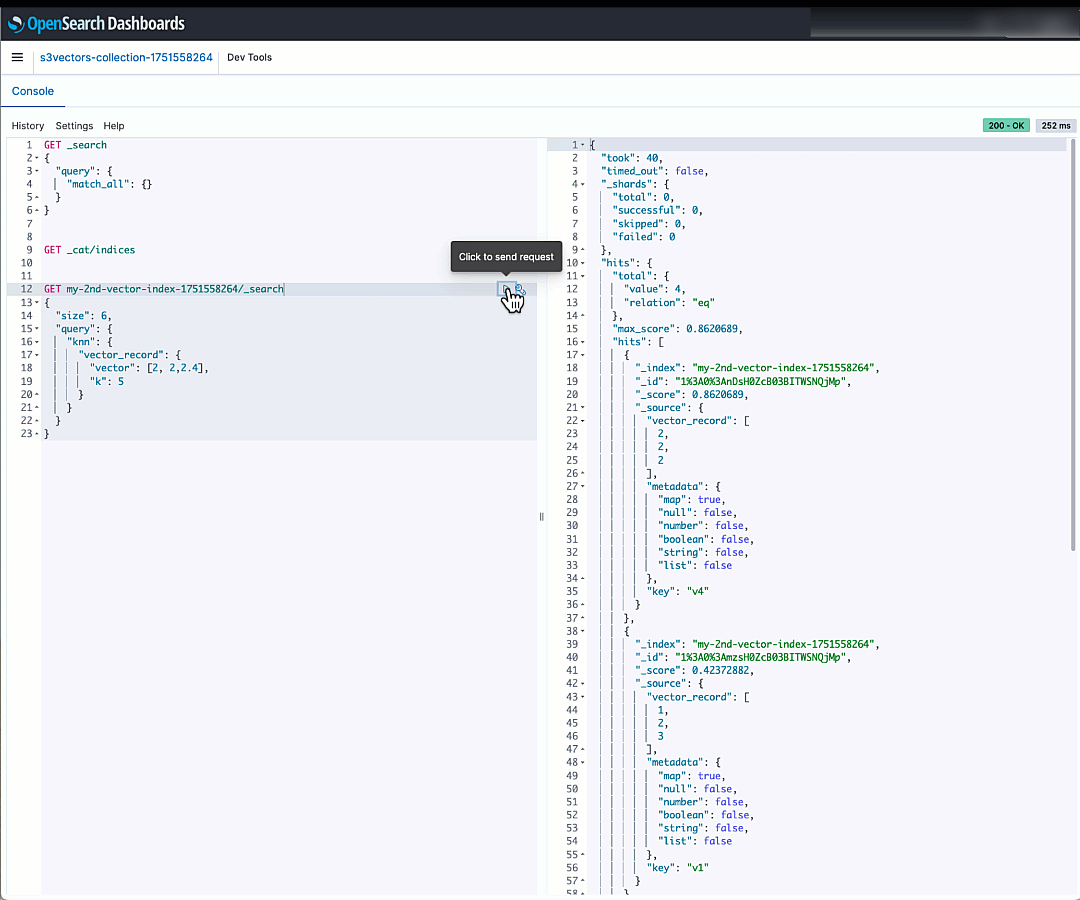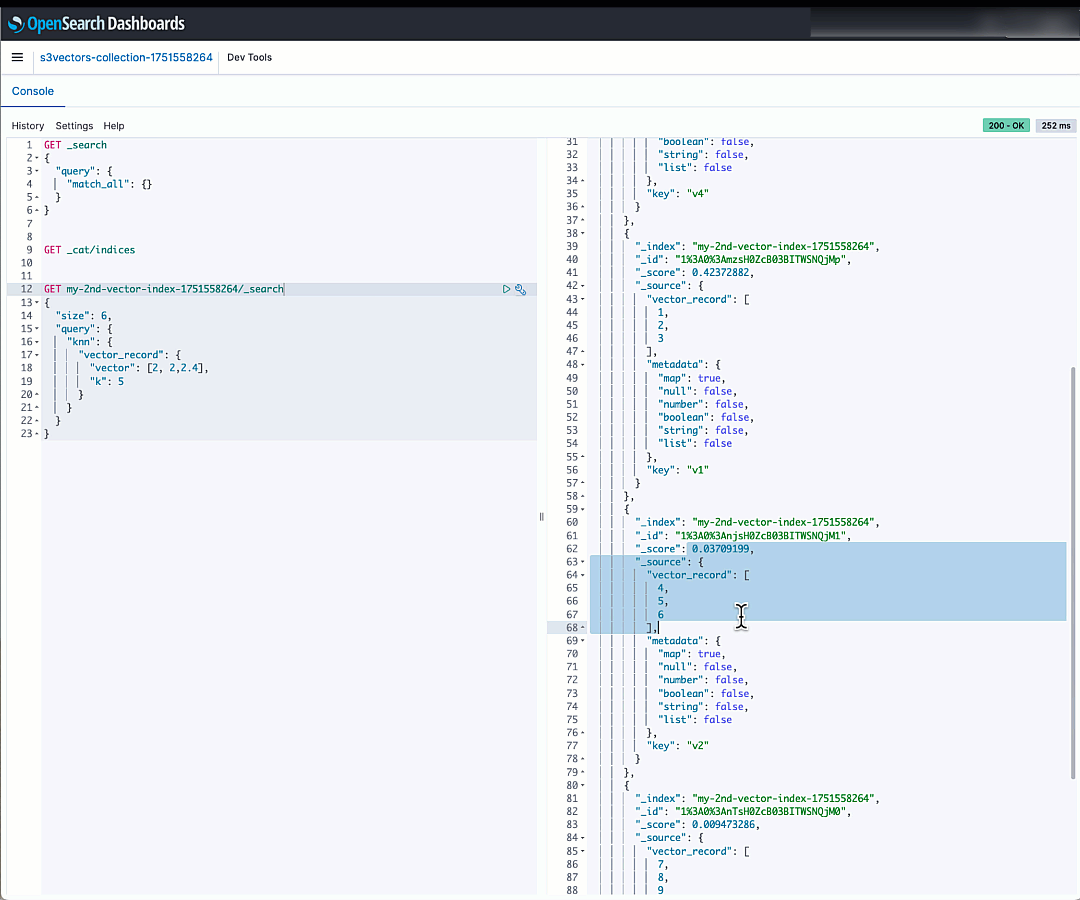
  1. You will now be taken to the Import history page in the OpenSearch Service console. Here you will see the new job that was created to migrate your S3 vector index into the OpenSearch serverless knn index. After the status changes from In Progress to Complete, you can connect to the new OpenSearch serverless collection and query your new OpenSearch knn index.

The following animation demonstrates how to connect to the new OpenSearch serverless collection and query your new OpenSearch knn index using Dev tools.

Cleanup

To avoid ongoing charges:

  1. For Pattern 1:
  1. For Pattern 2:
    • Delete the import task from the Import history section of the OpenSearch Service console. Deleting this task will remove both the OpenSearch vector collection and the OpenSearch Ingestion pipeline that was automatically created by the import task.

Conclusion

The innovative integration between Amazon S3 Vectors and Amazon OpenSearch Service marks a transformative milestone in vector search technology, offering unprecedented flexibility and cost-effectiveness for enterprises. This powerful combination delivers the best of both worlds: The renowned durability and cost efficiency of Amazon S3 merged seamlessly with the advanced AI search capabilities of OpenSearch. Organizations can now confidently scale their vector search solutions to billions of vectors while maintaining control over their latency, cost, and accuracy. Whether your priority is ultra-fast query performance with latency as low as 10ms through OpenSearch Service, or cost-optimized storage with impressive sub-second performance using S3 Vectors or implementing advanced search capabilities in OpenSearch, this integration provides the perfect solution for your specific needs. We encourage you to get started today by trying S3 Vectors engine in your OpenSearch managed clusters and testing the one-click export from S3 vector indexes to OpenSearch Serverless.

For more information, visit:


About the Authors

Sohaib Katariwala is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service based out of Chicago, IL. His interests are in all things data and analytics. More specifically he loves to help customers use AI in their data strategy to solve modern day challenges.

Mark Twomey is a Senior Solutions Architect at AWS focused on storage and data management. He enjoys working with customers to put their data in the right place, at the right time, for the right cost. Living in Ireland, Mark enjoys walking in the countryside, watching movies, and reading books.

Sorabh Hamirwasia is a senior software engineer at AWS working on the OpenSearch Project. His primary interest include building cost optimized and performant distributed systems.

Pallavi Priyadarshini is a Senior Engineering Manager at Amazon OpenSearch Service leading the development of high-performing and scalable technologies for search, security, releases, and dashboards.

Bobby Mohammed is a Principal Product Manager at AWS leading the Search, GenAI, and Agentic AI product initiatives. Previously, he worked on products across the full lifecycle of machine learning, including data, analytics, and ML features on SageMaker platform, deep learning training and inference products at Intel.

Introducing Amazon Bedrock AgentCore: Securely deploy and operate AI agents at any scale (preview)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-amazon-bedrock-agentcore-securely-deploy-and-operate-ai-agents-at-any-scale/

In just a few years, foundation models (FMs) have evolved from being used directly to create content in response to a user’s prompt, to now powering AI agents, a new class of software applications that use FMs to reason, plan, act, learn, and adapt in pursuit of user-defined goals with limited human oversight. This new wave of agentic AI is enabled by the emergence of standardized protocols such as Model Context Protocol (MCP) and Agent2Agent (A2A) that simplify how agents connect with other tools and systems.

In fact, building AI agents that can reliably perform complex tasks has become increasingly accessible thanks to open source frameworks like CrewAI, LangGraph, and Strands Agents. However, moving from a promising proof-of-concept to a production-ready agent that can scale to thousands of users presents significant challenges.

Instead of being able to focus on the core features of the agent, developers and AI engineers have to spend months building foundational infrastructure for session management, identity controls, memory systems, and observability—at the same time supporting security and compliance.

Today, we’re excited to announce the preview of Amazon Bedrock AgentCore, a comprehensive set of enterprise-grade services that help developers quickly and securely deploy and operate AI agents at scale using any framework and model, hosted on Amazon Bedrock or elsewhere.

More specifically, we are introducing today:

AgentCore Runtime – Provides sandboxed low-latency serverless environments with session isolation, supporting any agent framework including popular open source frameworks, tools, and models, and handling multimodal workloads and long-running agents.

AgentCore Memory – Manages session and long-term memory, providing relevant context to models while helping agents learn from past interactions.

AgentCore Observability – Offers step-by-step visualization of agent execution with metadata tagging, custom scoring, trajectory inspection, and troubleshooting/debugging filters.

AgentCore Identity – Enables AI agents to securely access AWS services and third-party tools and services such as GitHub, Salesforce, and Slack, either on behalf of users or by themselves with pre-authorized user consent.

AgentCore Gateway – Transforms existing APIs and AWS Lambda functions into agent-ready tools, offering unified access across protocols, including MCP, and runtime discovery.

AgentCore Browser – Provides managed web browser instances to scale your agents’ web automation workflows.

AgentCore Code Interpreter – Offers an isolated environment to run the code your agents generate.

These services can be used individually and are optimized to work together so developers don’t need to spend time piecing together components. AgentCore can work with open source or custom AI agent frameworks, giving teams the flexibility to maintain their preferred tools while gaining enterprise capabilities. To integrate these services into their existing code, developers can use the AgentCore SDK.

You can now discover, buy, and run pre-built agents and agent tools from AWS Marketplace with AgentCore Runtime. With just a few lines of code, your agents can securely connect to API-based agents and tools from AWS Marketplace with AgentCore Gateway to help you run complex workflows while maintaining compliance and control.

AgentCore eliminates tedious infrastructure work and operational complexity so development teams can bring groundbreaking agentic solutions to market faster.

Let’s see how this works in practice. I’ll share more info on the services as we use them.

Deploying a production-ready customer support assistant with Amazon Bedrock AgentCore (Preview)
When customers reach out with an email, it takes time to provide a reply. Customer support needs to check the validity of the email, find who the actual customer is in the customer relationship management (CRM) system, check their orders, and use product-specific knowledge bases to find the information required to prepare an answer.

An AI agent can simplify that by connecting to the internal systems, retrieve contextual information using a semantic data source, and draft a reply for the support team. For this use case, I built a simple prototype using Strands Agents. For simplicity and to validate the scenario, the internal tools are simulated using Python functions.

When I talk to developers, they tell me that similar prototypes, covering different use cases, are being built in many companies. When these prototypes are demonstrated to the company leadership and receive confirmation to proceed, the development team has to define how to go in production and satisfy the usual requirements for security, performance, availability, and scalability. This is where AgentCore can help.

Step 1 – Deploying to the cloud with AgentCore Runtime

AgentCore Runtime is a new service to securely deploy, run, and scale AI agents, providing isolation so that each user session runs in its own protected environment to help prevent data leakage—a critical requirement for applications handling sensitive data.

To match different security postures, agents can use different network configurations:

Sandbox – To only communicate with allowlisted AWS services.

Public – To run with managed internet access.

VPC-only (coming soon) – This option will allow to access resources hosted in a customer’s VPC or connected via AWS PrivateLink endpoints.

To deploy the agent to the cloud and get a secure, serverless endpoint with AgentCore Runtime, I add to the prototype a few lines of code using the AgentCore SDK to:

  • Import the AgentCore SDK.
  • Create the AgentCore app.
  • Specify which function is the entry point to invoke the agent.

Using a different or custom agent framework is a matter of replacing the agent invocation inside the entry point function.

Here’s the code of the prototype. The three lines I added to use AgentCore Runtime are the ones preceded by a comment.

from strands import Agent, tool
from strands_tools import calculator, current_time

# Import the AgentCore SDK
from bedrock_agentcore.runtime import BedrockAgentCoreApp

WELCOME_MESSAGE = """
Welcome to the Customer Support Assistant! How can I help you today?
"""

SYSTEM_PROMPT = """
You are an helpful customer support assistant.
When provided with a customer email, gather all necessary info and prepare the response email.
When asked about an order, look for it and tell the full description and date of the order to the customer.
Don't mention the customer ID in your reply.
"""

@tool
def get_customer_id(email_address: str):
    if email_address == "[email protected]":
        return { "customer_id": 123 }
    else:
        return { "message": "customer not found" }

@tool
def get_orders(customer_id: int):
    if customer_id == 123:
        return [{
            "order_id": 1234,
            "items": [ "smartphone", "smartphone USB-C charger", "smartphone black cover"],
            "date": "20250607"
        }]
    else:
        return { "message": "no order found" }

@tool
def get_knowledge_base_info(topic: str):
    kb_info = []
    if "smartphone" in topic:
        if "cover" in topic:
            kb_info.append("To put on the cover, insert the bottom first, then push from the back up to the top.")
            kb_info.append("To remove the cover, push the top and bottom of the cover at the same time.")
        if "charger" in topic:
            kb_info.append("Input: 100-240V AC, 50/60Hz")
            kb_info.append("Includes US/UK/EU plug adapters")
    if len(kb_info) > 0:
        return kb_info
    else:
        return { "message": "no info found" }

# Create an AgentCore app
app = BedrockAgentCoreApp()

agent = Agent(
    system_prompt=SYSTEM_PROMPT,
    tools=[calculator, current_time, get_customer_id, get_orders, get_knowledge_base_info]
)

# Specify the entrypoint function invoking the agent
@app.entrypoint
def invoke(payload, context: RequestContext):
    """Handler for agent invocation"""
    user_message = payload.get(
        "prompt", "No prompt found in input, please guide customer to create a json payload with prompt key"
    )
    result = agent(user_message)
    return {"result": result.message}

if __name__ == "__main__":
    app.run()

I install the AgentCore SDK and the starter toolkit in the Python virtual environment:

pip install bedrock-agentcore bedrock-agentcore-starter-toolkit

After I activate the virtual environment, I have access to the AgentCore command line interface (CLI) provided by the starter toolkit.

First, I use agentcore configure --entrypoint my_agent.py -er <IAM_ROLE_ARN> to configure the agent, passing the AWS Identity and Access Management (IAM) role that the agent will assume. In this case, the agent needs access to Amazon Bedrock to invoke the model. The role can give access to other AWS resources used by an agent, such as an Amazon Simple Storage Service (Amazon S3) bucket or a Amazon DynamoDB table.

I launch the agent locally with agentcore launch --local. When running locally, I can interact with the agent using agentcore invoke --local <PAYLOAD>. The payload is passed to the entry point function. Note that the JSON syntax of the invocations is defined in the entry point function. In this case, I look for prompt in the JSON payload, but can use a different syntax depending on your use case.

When I am satisfied by local testing, I use agentcore launch to deploy to the cloud.

After the deployment is succesful and an endpoint has been created, I check the status of the endpoint with agentcore status and invoke the endpoint with agentcore invoke <PAYLOAD>. For example, I pass a customer support request in the invocation:

agentcore invoke '{"prompt": "From: [email protected] – Hi, I bought a smartphone from your store. I am traveling to Europe next week, will I be able to use the charger? Also, I struggle to remove the cover. Thanks, Danilo"}'

Step 2 – Enabling memory for context

After an agent has been deployed in the AgentCore Runtime, the context needs to be persisted to be available for a new invocation. I add AgentCore Memory to maintain session context using its short-term memory capabilities.

First, I create a memory client and the memory store for the conversations:

from bedrock_agentcore.memory import MemoryClient

memory_client = MemoryClient(region_name="us-east-1")

memory = memory_client.create_memory_and_wait(
    name="CustomerSupport", 
    description="Customer support conversations"
)

I can now use create_event to stores agent interactions into short-term memory:

memory_client.create_event(
    memory_id=memory.get("id"), # Identifies the memory store
    actor_id="user-123",        # Identifies the user
    session_id="session-456",   # Identifies the session
    messages=[
        ("Hi, ...", "USER"),
        ("I'm sorry to hear that...", "ASSISTANT"),
        ("get_orders(customer_id='123')", "TOOL"),
        . . .
    ]
)

I can load the most recent turns of a conversations from short-term memory using list_events:

conversations = memory_client.list_events(
    memory_id=memory.get("id"), # Identifies the memory store
    actor_id="user-123",        # Identifies the user 
    session_id="session-456",   # Identifies the session
    max_results=5               # Number of most recent turns to retrieve
)

With this capability, the agent can maintain context during long sessions. But when a users come back with a new session, the conversation starts blank. Using long-term memory, the agent can personalize user experiences by retaining insights across multiple interactions.

To extract memories from a conversation, I can use built-in AgentCore Memory policies for user preferences, summarization, and semantic memory (to capture facts) or create custom policies for specialized needs. Data is stored encrypted using a namespace-based storage for data segmentation.

I change the previous code creating the memory store to include long-term capabilities by passing a semantic memory strategy. Note that an existing memory store can be updated to add strategies. In that case, the new strategies are applied to newer events.

memory = memory_client.create_memory_and_wait(
    name="CustomerSupport", 
    description="Customer support conversations",
    strategies=[{
        "semanticMemoryStrategy": {
            "name": "semanticFacts",
            "namespaces": ["/facts/{actorId}"]
        }
    }]
)

After long-term memory has been configured for a memory store, calling create_event will automatically apply those strategies to extract information from the conversations. I can then retrieve memories extracted from the conversation using a semantic query:

memories = memory_client.retrieve_memories(
    memory_id=memory.get("id"),
    namespace="/facts/user-123",
    query="smartphone model"
)

In this way, I can quickly improve the user experience so that the agent remembers customer preferences and facts that are outside of the scope of the CRM and use this information to improve the replies.

Step 3 – Adding identity and access controls

Without proper identity controls, access from the agent to internal tools always uses the same access level. To follow security requirements, I integrate AgentCore Identity so that the agent can use access controls scoped to the user’s or agent’s identity context.

I set up an identity client and create a workload identity, a unique identifier that represents the agent within the AgentCore Identity system:

from bedrock_agentcore.services.identity import IdentityClient

identity_client = IdentityClient("us-east-1")
workload_identity = identity_client.create_workload_identity(name="my-agent")

Then, I configure the credential providers, for example:

google_provider = identity_client.create_oauth2_credential_provider(
    {
        "name": "google-workspace",
        "credentialProviderVendor": "GoogleOauth2",
        "oauth2ProviderConfigInput": {
            "googleOauth2ProviderConfig": {
                "clientId": "your-google-client-id",
                "clientSecret": "your-google-client-secret",
            }
        },
    }
)

perplexity_provider = identity_client.create_api_key_credential_provider(
    {
        "name": "perplexity-ai",
        "apiKey": "perplexity-api-key"
    }
)

I can then add the @requires_access_token Python decorator (passing the provider name, the scope, and so on) to the functions that need an access token to perform their activities.

Using this approach, the agent can verify the identity through the company’s existing identity infrastructure, operate as a distinct, authenticated identity, act with scoped permissions and integrate across multiple identity providers (such as Amazon Cognito, Okta, or Microsoft Entra ID) and service boundaries including AWS and third-party tools and services (such as Slack, GitHub, and Salesforce).

To offer robust and secure access controls while streamlining end-user and agent builder experiences, AgentCore Identity implements a secure token vault that stores users’ tokens and allows agents to retrieve them securely.

For OAuth 2.0 compatible tools and services, when a user first grants consent for an agent to act on their behalf, AgentCore Identity collects and stores the user’s tokens issued by the tool in its vault, along with securely storing the agent’s OAuth client credentials. Agents, operating with their own distinct identity and when invoked by the user, can then access these tokens as needed, reducing the need for frequent user consent.

When the user token expires, AgentCore Identity triggers a new authorization prompt to the user for the agent to obtain updated user tokens. For tools that use API keys, AgentCore Identity also stores these keys securely and gives agents controlled access to retrieve them when needed. This secure storage streamlines the user experience while maintaining robust access controls, enabling agents to operate effectively across various tools and services.

Step 4 – Expanding agent capabilities with AgentCore Gateway

Until now, all internal tools are simulated in the code. Many agent frameworks, including Strands Agents, natively support MCP to connect to remote tools. To have access to internal systems (such as CRM and order management) via an MCP interface, I use AgentCore Gateway.

With AgentCore Gateway, the agent can access AWS services using Smithy models, Lambda functions, and internal APIs and third-party providers using OpenAPI specifications. It employs a dual authentication model to have secure access control for both incoming requests and outbound connections to target resources. Lambda functions can be used to integrate external systems, particularly applications that lack standard APIs or require multiple steps to retrieve information.

AgentCore Gateway facilitates cross-cutting features that most customers would otherwise need to build themselves, including authentication, authorization, throttling, custom request/response transformation (to match underlying API formats), multitenancy, and tool selection.

The tool selection feature helps find the most relevant tools for a specific agent’s task. AgentCore Gateway brings a uniform MCP interface across all these tools, using AgentCore Identity to provide an OAuth interface for tools that do not support OAuth out of the box like AWS services.

Step 5 – Adding capabilities with AgentCore Code Interpreter and Browser tools

To answer to customer requests, the customer support agent needs to perform calculations. To simplify that, I use the AgentCode SDK to add access to the AgentCore Code Interpreter.

Similarly, some of the integrations required by the agent don’t implement a programmatic API but need to be accessed through a web interface. I give access to the AgentCore Browser to let the agent navigate those web sites autonomously.

Step 6 – Gaining visibility with observability

Now that the agent is in production, I need visibility into its activities and performance. AgentCore provides enhanced observability to help developers effectively debug, audit, and monitor their agent performance in production. It comes with built-in dashboards to track essential operational metrics such as session count, latency, duration, token usage, error rates, and component-level latency and error breakdowns. AgentCore also gives visibility into an agent’s behavior by capturing and visualizing both the end-to-end traces, as well as “spans” that capture each step of the agent workflow including tool invocations, memory

The built-in dashboards offered by this service help reveal performance bottlenecks and identify why certain interactions might fail, enabling continuous improvement and reducing the mean time to detect (MTTD) and mean time to repair (MTTR) in case of issues.

AgentCore supports OpenTelemetry to help integrate agent telemetry data with existing observability platforms, including Amazon CloudWatch, Datadog, LangSmith, and Langfuse.

Step 7 – Conclusion

Through this journey, we transformed a local prototype into a production-ready system. Using AgentCore modular approach, we implemented enterprise requirements incrementally—from basic deployment to sophisticated memory, identity management, and tool integration—all while maintaining the existing agent code.

Things to know
Amazon Bedrock AgentCore is available in preview in US East (N. Virginia), US West (Oregon), Asia Pacific (Sydney), and Europe (Frankfurt). You can start using AgentCore services through the AWS Management Console , the AWS Command Line Interface (AWS CLI), the AWS SDKs, or via the AgentCore SDK.

You can try AgentCore services at no charge until September 16, 2025. Standard AWS pricing applies to any additional AWS Services used as part of using AgentCore (for example, CloudWatch pricing will apply for AgentCore Observability). Starting September 17, 2025, AWS will bill you for AgentCore service usage based on this page.

Whether you’re building customer support agents, workflow automation, or innovative AI-powered experiences, AgentCore provides the foundation you need to move from prototype to production with confidence.

To learn more and start deploying production-ready agents, visit the AgentCore documentation. For code examples and integration guides, check out the AgentCore samples GitHub repo.

Join the AgentCore Preview Discord server to provide feedback and discuss use cases. We’d like to hear from you!

— Danilo
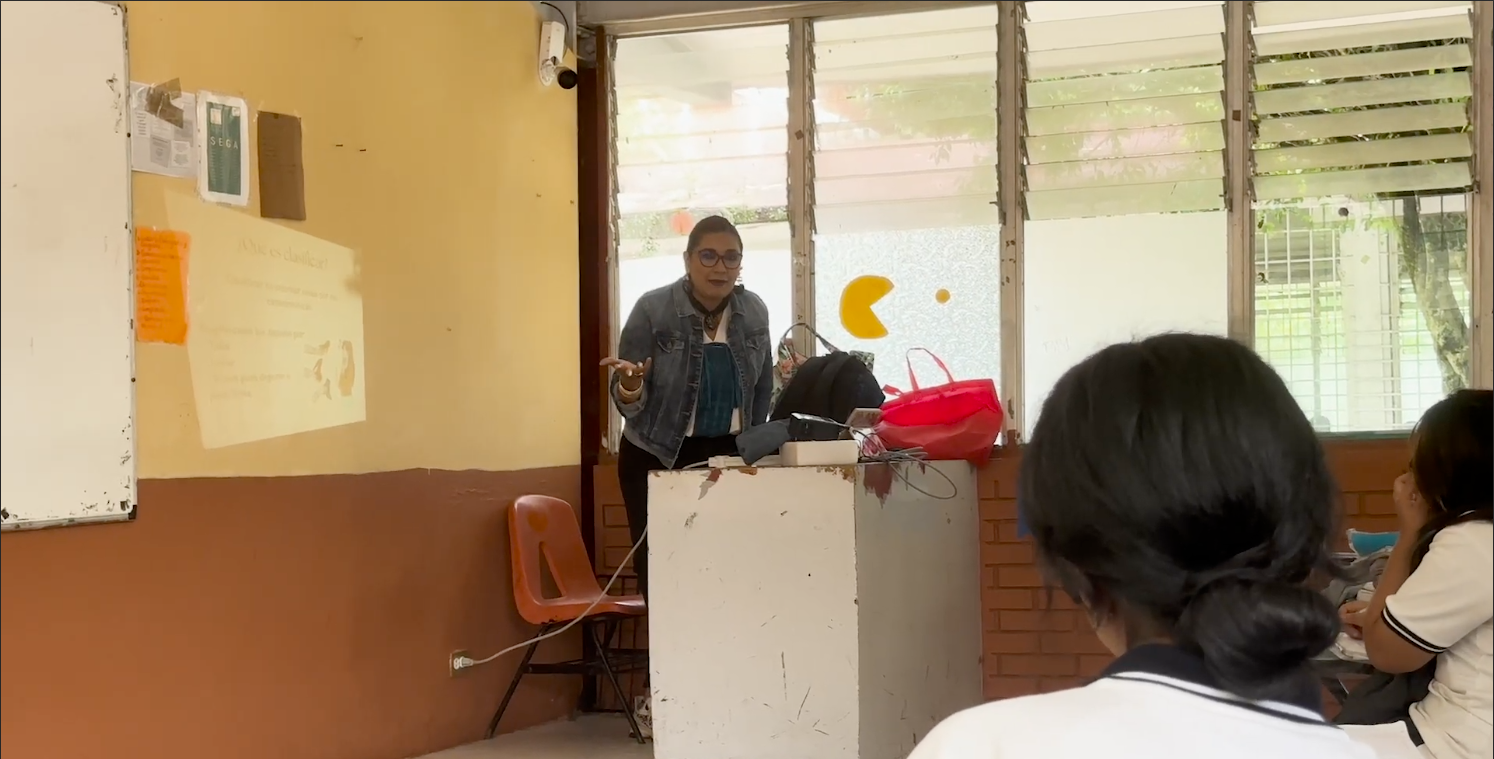
Streamline the path from data to insights with new Amazon SageMaker Catalog capabilities

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/streamline-the-path-from-data-to-insights-with-new-amazon-sagemaker-capabilities/

Modern organizations manage data across multiple disconnected systems—structured databases, unstructured files, and separate visualization tools—creating barriers that slow analytics workflows and limit insight generation. Separate visualization platforms often create barriers that prevent teams from extracting comprehensive business insights.

These disconnected workflows prevent your organizations from maximizing your data investments, creating delays in decision making and missed opportunities for comprehensive analysis that combines multiple data types.

Starting today, you can use three new capabilities in Amazon SageMaker to accelerate your path from raw data to actionable insights:

  • Amazon QuickSight integration – Launch Amazon QuickSight directly from Amazon SageMaker Unified Studio to build dashboards using your project data, then publish them to the Amazon SageMaker Catalog for broader discovery and sharing across your organization.
  • Amazon SageMaker adds support for Amazon S3 general purpose buckets and Amazon S3 Access Grants in SageMaker Catalog– Make data stored in Amazon S3 general purpose buckets easier for teams to find, access, and collaborate on all types of data including unstructured data, while maintaining fine-grained access control using Amazon S3 Access Grants.
  • Automatic data onboarding from your lakehouse – Automatic onboarding of existing AWS Glue Data Catalog (GDC) datasets from the lakehouse architecture into SageMaker Catalog, without manual setup.

These new SageMaker capabilities address the complete data lifecycle within a unified and governed experience. You get automatic onboarding of existing structured data from your lakehouse, seamless cataloging of unstructured data content in Amazon S3, and streamlined visualization through QuickSight—all with consistent governance and access controls.

Let’s take a closer look at each capability.

Amazon SageMaker and Amazon QuickSight Integration
With this integration, you can build dashboards in Amazon QuickSight using data from your Amazon SageMaker projects. When you launch QuickSight from Amazon SageMaker Unified Studio, Amazon SageMaker automatically creates the QuickSight dataset and organizes it in a secured folder accessible only to project members.

Furthermore, the dashboards you build stay within this folder and automatically appear as assets in your SageMaker project, where you can publish them to the SageMaker Catalog and share them with users or groups in your corporate directory. This keeps your dashboards organized, discoverable, and governed within SageMaker Unified Studio.

To use this integration, both your Amazon SageMaker Unified Studio domain and QuickSight account must be integrated with AWS IAM Identity Center using the same IAM Identity Center instance. Additionally, your QuickSight account must exist in the same AWS account where you want to enable the QuickSight blueprint. You can learn more about the prerequisites on Documentation page. 

After these prerequisites are met, you can enable the blueprint for Amazon QuickSight by navigating to the Amazon SageMaker console and choosing the Blueprints tab. Then find Amazon QuickSight and follow the instructions.

You also need to configure your SQL analytics project profile to include Amazon QuickSight in Add blueprint deployment settings.

To learn more on onboarding setup, refer to the Documentation page.

Then, when you create a new project, you need to use the SQL analytics profile.

With your project created, you can start building visualizations with QuickSight. You can navigate to the Data tab, select the table or view to visualize, and choose Open in QuickSight under Actions.

This will redirect you to the Amazon QuickSight transactions dataset page and you can choose USE IN ANALYSIS to begin exploring the data.

When you create a project with the QuickSight blueprint, SageMaker Unified Studio automatically provisions a restricted QuickSight folder per project where SageMaker scopes all new assets—analyses, datasets, and dashboards. The integration maintains real-time folder permission sync, keeping QuickSight folder access permissions aligned with project membership.

Amazon Simple Storage Service (S3) general purpose buckets integration
Starting today, SageMaker adds support for S3 general purpose buckets in SageMaker Catalog to increase discoverability and allows granular permissions through S3 Access Grants, enabling users to govern data, including sharing and managing permissions. Data consumers, such as data scientists, engineers, and business analysts, can now discover and access S3 assets through SageMaker Catalog. This expansion also enables data producers to govern security controls on any S3 data asset through a single interface.

To use this integration, you need appropriate S3 general purpose bucket permissions, and your SageMaker Unified Studio projects must have access to the S3 buckets containing your data. Learn more about prerequisites on Amazon S3 data in Amazon SageMaker Unified Studio Documentation page.

You can add a connection to an existing S3 bucket.

When it’s connected, you can browse accessible folders and create discoverable assets by choosing on the bucket or a folder and selecting Publish to Catalog.

This action creates a SageMaker Catalog asset of type “S3 Object Collection” and opens an asset details page where users can augment business context to improve search and discoverability. Once published, data consumers can discover and subscribe to these cataloged assets. When data consumers subscribe to “S3 Object Collection” assets, SageMaker Catalog automatically grants access using S3 Access Grants upon approval, enabling cross-team collaboration while ensuring only the right users have the right access.

When you have access, now you can process your unstructured data in Amazon SageMaker Jupyter notebook. Following screenshot is an example to process image in medical use case.

If you have structured data, you can query your data using Amazon Athena or process using Spark in notebooks.

With this access granted through S3 Access Grants, you can seamlessly incorporate S3 data into my workflows—analyzing it in notebooks, combining it with structured data in the lakehouse and Amazon Redshift for comprehensive analytics. You can access unstructured data such as documents, images in JupyterLab notebooks to train ML models, or generate queryable insights.

Automatic data onboarding from your lakehouse
This integration automatically onboards all your lakehouse datasets into SageMaker Catalog. The key benefit for you is to bring AWS Glue Data Catalog (GDC) datasets into SageMaker Catalog, eliminating manual setup for cataloging, sharing, and governing them centrally.

This integration requires an existing lakehouse setup with Data Catalog containing your structured datasets.

When you set up a SageMaker domain, SageMaker Catalog automatically ingests metadata from all lakehouse databases and tables. This means you can immediately explore and use these datasets from within SageMaker Unified Studio without any configuration.

The integration helps you to start managing, governing, and consuming these assets from within SageMaker Unified Studio, applying the same governance policies and access controls you can use for other data types while unifying technical and business metadata.

Additional things to know
Here are a couple of things to note:

  • Availability – These integrations are available in all commercial AWS Regions where Amazon SageMaker is supported.
  • Pricing – Standard SageMaker Unified Studio, QuickSight, and Amazon S3 pricing applies. No additional charges for the integrations themselves.
  • Documentation – You can find complete setup guides in the SageMaker Unified Studio Documentation.

Get started with these new integrations through the Amazon SageMaker Unified Studio console.

Happy building!
— Donnie

TwelveLabs video understanding models are now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/twelvelabs-video-understanding-models-are-now-available-in-amazon-bedrock/

Earlier this year, we preannounced that TwelveLabs video understanding models were coming to Amazon Bedrock. Today, we’re announcing the models are now available for searching through videos, classifying scenes, summarizing, and extracting insights with precision and reliability.

TwelveLabs has introduced Marengo, a video embedding model proficient at performing tasks such as search and classification, and Pegasus, a video language model that can generate text based on video data. These models are trained on Amazon SageMaker HyperPod to deliver groundbreaking video analysis that provides text summaries, metadata generation, and creative optimization.

With the TwelveLabs models in Amazon Bedrock, you can find specific moments using natural language video search capabilities like “show me the first touchdown of the game” or “find the scene where the main characters first meet” and instantly jump to those exact moments. You can also build applications to understand video content by generating descriptive text such as titles, topics, hashtags, summaries, chapters, or highlights for discovering insights and connections without requiring predefined labels or categories.

For example, you can find recurring themes in customer feedback or spot product usage patterns that weren’t obvious before. Whether you have hundreds or thousands of hours of video content, you can now transform that entire library into a searchable knowledge resource while maintaining enterprise-grade security and performance.

Let’s take a look at the Marengo and Pegasus videos that TwelveLabs has published.

You can transform video workflows with these models across industries. Media producers and editors can instantly locate specific scenes or dialogue, which means you can focus on storytelling rather than sifting through hours of footage. Marketing teams are streamlining their advertising workflows by quickly personalizing content to resonate with various audiences, while security teams are using the technology to proactively identify potential risks by spotting patterns across multiple video feeds.

Getting started with TwelveLabs models in Amazon Bedrock
Before getting started, if you’re new to using TwelveLabs models, go to the Amazon Bedrock console and choose Model access in the bottom left navigation pane. To access the latest TwelveLabs models, request access for Marengo Embed 2.7 and Pegasus 1.2 in TwelveLabs.

To use TwelveLabs models in Amazon Bedrock, choose Chat/Text Playground under Test in the left navigation pane. Choose Select model, select TwelveLabs as the category and Pegasus as the model, and then choose Apply.

For searching or generating text from your video, you should upload your video to an Amazon Simple Storage Service (Amazon S3) bucket or input Base64-formatted video string.

I will use a sample video generated with Amazon Nova Reel with a prompt: “A cute raccoon playing guitar underwater.”

Enter the S3 URI of your uploaded video and the S3 Bucket Owner, and then run your prompt: “Tell me about the video by timeline”.

You can get following model response:

The video opens with an underwater scene featuring a sandy seabed and swaying seaweed, creating a serene atmosphere. At around 5 seconds, a raccoon appears, swimming towards the camera with a curious expression. By 10 seconds, the raccoon is seen swimming near the seabed. The focus then shifts to a group of koi fish swimming gracefully near the seabed from 11 to 13 seconds.

At 14 seconds, the scene transitions to an ukulele resting on the seabed, with the camera zooming in to highlight its details. The raccoon reappears at 20 seconds, swimming among the koi fish, and by 23 seconds, it begins to play the ukulele. The raccoon continues to play the ukulele from 29 to 41 seconds, with the koi fish swimming around it, adding a lively and colorful touch to the underwater setting.

From 42 to 49 seconds, the raccoon is shown playing the ukulele with the koi fish swimming around it. The video concludes with a screen displaying "Video generated with Amazon Novo Reel 1.1" and "Available in Amazon Bedrock" from 50 to 54 seconds, followed by the AWS logo from 55 to 57 seconds.

The TwelveLabs models can be easily integrated into your applications using the Amazon Bedrock Converse API, which provides a unified interface for conversational AI interactions.

Here’s an example of how to use the AWS SDK for Python (Boto3) with the TwelveLabs Pegasus model:

import boto3
import json
import os

AWS_REGION = "us-east-1"
MODEL_ID = "twelvelabs.pegasus-1-2-v1:0"
VIDEO_PATH = "sample.mp4"

def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

bedrock_runtime = boto3.client(
    service_name="bedrock-runtime",
    region_name=AWS_REGION
)

request_body = {
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "inputPrompt": "tell me about the video",
                    "mediaSource: {
                        "base64String": read_file(VIDEO_PATH)
                    }
                },
            ],
        }
    ]
}

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=request_body["messages"]
)

print(response["output"]["message"]["content"][-1]["text"])

The TwelveLabs Marengo Embed 2.7 model generates vector embeddings from video, text, audio, or image inputs. These embeddings can be used for similarity search, clustering, and other machine learning (ML) tasks. The model supports asynchronous inference through the Bedrock AsyncInvokeModel API.

For video source, you can request JSON format for the TwelveLabs Marengo Embed 2.7 model using the AsyncInvokeModel API.

{
    "modelId": "twelvelabs.marengo-embed-2.7",
    "modelInput": {
        "inputType": "video",
        "mediaSource": {
            "s3Location": {
                "uri": "s3://your-video-object-s3-path",
                "bucketOwner": "your-video-object-s3-bucket-owner-account"
            }
        }
    },
    "outputDataConfig": {
        "s3OutputDataConfig": {
            "s3Uri": "s3://your-bucket-name"
        }
    }
}

You can get a response delivered to the specified S3 location.

{
    "embedding": [0.345, -0.678, 0.901, ...],
    "embeddingOption": "visual-text",
    "startSec": 0.0,
    "endSec": 5.0
}

To help you get started, check out a broad range of code examples for multiple use cases and a variety of programming languages. To learn more, visit TwelveLabs Pegasus 1.2 and TwelveLabs Marengo Embed 2.7 in the AWS Documentation.

Now available
TwelveLabs models are generally available today in Amazon Bedrock: the Marengo model in the US East (N. Virginia), Europe (Ireland), and Asia Pacific (Seoul) Region, and the Pegasus model in US West (Oregon), and Europe (Ireland) Region accessible with cross-Region inference from US and Europe Regions. Check the full Region list for future updates. To learn more, visit the TwelveLabs in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give TwelveLabs models a try on the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Amazon Bedrock baseline architecture in an AWS landing zone

Post Syndicated from Abdel-Rahman Awad original https://aws.amazon.com/blogs/architecture/amazon-bedrock-baseline-architecture-in-an-aws-landing-zone/

As organizations increasingly adopt Amazon Bedrock to build and deploy large-scale AI applications, it’s important that they understand and adopt critical network access controls to protect their data and workloads. These generative AI-enabled applications might have access to sensitive or confidential information within their knowledge bases, Retrieval Augmented Generation (RAG) data sources, or models themselves, which could pose a risk if exposed to unauthorized parties. Additionally, organizations might want to limit access to certain AI models to specific teams or services, making sure only authorized users can use the most powerful capabilities. Another important consideration is cost optimization, because organizations need to be able to monitor and control access to manage various aspects of their cloud spending.

In this post, we explore the Amazon Bedrock baseline architecture and how you can secure and control network access to your various Amazon Bedrock capabilities within AWS network services and tools. We discuss key design considerations, such as using Amazon VPC Lattice auth policies, Amazon Virtual Private Cloud (Amazon VPC) endpoints, and AWS Identity and Access Management (IAM) to restrict and monitor access to your Amazon Bedrock capabilities.

By the end of this post, you will have a better understanding of how to configure your AWS landing zone to establish secure and controlled network connectivity to Amazon Bedrock across your organization using VPC Lattice.

Solution overview

Addressing the aforementioned challenges requires a well-designed network architecture and security controls. For this, we use the standard AWS Landing Zone Accelerator networking configuration. It provides a good starting point for managing network communication across multiple accounts. On top of the AWS Landing Zone Accelerator network design, we add two shared accounts.

In this solution design, we create a centralized architecture for managing organization AI capabilities across different accounts. The architecture consists of three main parts that work together to provide secure and controlled access to AI services:

  • Service network account – This account serves as the central networking hub for the organization, managing network connectivity and access policies. Through this account, network administrators can centrally manage and control access to AI services across the organization. The account follows AWS Landing Zone Accelerator networking practices that scale with enterprise organizational needs.
  • Generative AI account – This account hosts the organization’s Amazon Bedrock capabilities and serves as the central point for AI/ML management. The organization’s AI/ML scientists and prompt engineers will centrally build and manage Amazon Bedrock capabilities. The account provides access to various large language models (LLMs) through Amazon Bedrock by using VPC interface endpoints, while also enabling centralized monitoring of cost consumption and access patterns.
  • Workload accounts (dev, test, prod) – These accounts represent different environments where teams develop and deploy applications that consume AI services. Through secure network connections established through the service network account, these workload accounts can access the AI capabilities hosted in the generative AI account. This separation enforces proper isolation between development, testing, and production workloads while maintaining secure access to AI services.
Amazon Bedrock baseline architecture in an AWS landing zone

Amazon Bedrock baseline architecture in an AWS landing zone

The following diagram illustrates the solution architecture.

The service network account has its own VPC Lattice service network—a centralized networking construct that enables service-to-service communication across your organization, which is shared with workload accounts using AWS Resource Access Manager (AWS RAM) to enable VPC Lattice Service network sharing.

Workload accounts (dev, test, prod) establish VPC associations with the shared VPC Lattice service network by creating a service network association in their VPC. When an application in these accounts makes a request, it first queries the VPC resolver for DNS resolution. The resolver routes the traffic to the VPC Lattice service network.

Access control is implemented through an VPC Lattice auth policy. The service network policies determine which accounts can access the VPC Lattice service network, and service-level policies control access to specific AI services and define what actions each account can perform.

In the central AI services account, we find the proxy layer, we create a VPC Lattice service that points to a proxy layer, which acts as a single entry point, providing workload accounts access to Amazon Bedrock. This proxy layer then connects to Amazon Bedrock through VPC endpoints. Through this setup, the AI team can configure which foundation models (FMs) are available and manage access permissions for different workload accounts. After the necessary policies and connections are in place, workload accounts can access Amazon Bedrock capabilities through the established secure pathway. This setup enables secure, cross-account access to AI services while maintaining centralized control and monitoring.

Network components

We use VPC Lattice, which is a fully managed application networking service that helps you simplify network connectivity, security, and monitoring for service-to-service communication needs. With VPC Lattice, organizations can achieve a centralized connectivity pattern to control and monitor access to the services required for building generative AI applications.

For details about VPC Lattice, refer to the Amazon VPC Lattice User Guide. The following is an overview of the constructs you can use in setting up the centralized pattern in this solution:

  • VPC Lattice service network – You can use the VPC Lattice service network to provide central connectivity and security to the central AI services account. The service network is a logical grouping mechanism that simplifies how you can enable connectivity across VPCs or accounts, and apply common security policies for application communication patterns. You can create a service network in an account and share it with other accounts within or outside AWS Organizations using AWS RAM.
  • VPC Lattice service – In a service network, you can associate a VPC Lattice service, which consists of a listener (protocol and port number), routing rules that allow for control of the application flow (for example, path, method, header-based, or weighted routing), and target group, which defines the application infrastructure. A service can have multiple listeners to meet various client capabilities. Supported protocols include HTTP, HTTPS, gRPC, and TLS. The path-based routing allows control to various high-performing FMs and other capabilities you would need to build a generative AI application.
  • Proxy layer – You use a proxy layer for the VPC Lattice service target group. The proxy layer can be built based on your organization’s preference of AWS services, such as AWS Lambda, AWS Fargate, or Amazon Elastic Kubernetes Service (Amazon EKS). The purpose of the proxy layer is to provide a single entry point to access LLMs, knowledge bases, and other capabilities that are tested and approved according to your organization’s compliance requirements.
  • VPC Lattice auth policies – For security, you use VPC Lattice auth policies. VPC Lattice auth policies are specified using the same syntax as IAM policies. You can apply an auth policy to VPC Lattice service network as well as to the VPC Lattice service.
  • Fully Qualified Domain Names –To facilitate service discovery, VPC Lattice supports custom domain names for your services and resources, and maintains a Fully Qualified Domain Name (FQDN) for each VPC Lattice service and resource you define. You can use these FQDNs in your Amazon Route 53 private hosted zone configurations, and empower business units or teams to discover and access services and resources.
  • Service network VPC – Business units or teams can access generative AI services in a service network using service network VPC associations or a service network VPC endpoint.
  • Monitoring – You can choose to enable monitoring at the VPC Lattice service network level and VPC Lattice service level. VPC Lattice generates metrics and logs for requests and responses, making it more efficient to monitor and troubleshoot applications

The preceding guidance takes a “secure by default” approach—you must be explicit about which features, models, and so on should be accessed by which business unit. The setup also enables you to implement a defense-in-depth strategy at multiple layers of the network:

  • The first level of defense is that business team needs to connect to the service network in order to get access to the generative AI service through the central AI service account.
  • The second level includes network-level security protections in the business team’s VPC for the service network, such as security groups and network access control lists (ACLs). By using these, you can allow access to specific workloads or teams in a VPC.
  • The third level is through the VPC Lattice auth policy, which you can apply at two layers: at the service network level to allow authenticated requests within the organization, and at the service level to allow access to specific models and features.

VPC Lattice auth policy

This solution makes it possible to centrally manage access to Amazon Bedrock resources across your organization. This approach uses an VPC Lattice auth policy to centrally control Amazon Bedrock resources and manage it from one location across all the organization accounts.

Typically, the auth policy on the service network is operated by the network or cloud administrator. For example, allowing only authenticated requests from specific workloads or teams in your AWS organization. In the following example, access is granted to invoke the generated AI service for authenticated requests and to principals that are part of the o-123456example organization:

{
   "Version": "2012-10-17",
   "Statement": [
      {
         "Effect": "Allow",
         "Principal": "*",
         "Action": "vpc-lattice-svcs:Invoke",
         "Resource": "*",
         "Condition": {
            "StringEquals": {
               "aws:PrincipalOrgID": [ 
                  "o-123456example"
               ]
            }
         }
      }
   ]
}

The auth policy at the service level is managed by the central AI service team to set fine-grained controls, which can be more restrictive than the coarse-grained authorization applied at the service network level. For example, the following policy restricts access to claude-3-haiku for only business-team1:

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Effect": "Allow",
         "Principal": {
            "AWS": [
               "arn:aws:iam::<account-number>:role/businss-team1"
            ]
         },
         "Action": "vpc-lattice-svcs:Invoke",
         "Resource": [
            "arn:aws:vpc-lattice:<aws-region>:<account-number>:service/svc-0123456789abcdef0/*"
         ],
         "Condition": {
            "StringEquals": {
               "vpc-lattice-svcs:RequestQueryString/modelid": "claude-3-haiku"            }
         }
      }
   ]
}

Monitoring and tracking

This design employs three monitoring approaches, using Amazon CloudWatch, AWS CloudTrail, and VPC Lattice access logs. This strategy provides a view of service usage, security, and performance.

CloudWatch metrics offer real-time monitoring of VPC Lattice service performance and usage. CloudWatch tracks metrics such as request counts and response times for Amazon Bedrock related endpoints, allowing for the setup of alarms for proactive management of service health and capacity. This enables monitoring of overall usage patterns of Amazon Bedrock models across different business units, facilitating capacity planning and resource allocation. CloudTrail provides detailed API-level auditing of Amazon Bedrock related actions. It logs cross-account access attempts and interactions with Amazon Bedrock services, providing a compliance and security audit trail. This tracking of who is accessing which Amazon Bedrock models, when, and from which accounts helps organizations adhere to their organizational policies.VPC Lattice access logs provide detailed insights into HTTP/HTTPS requests to Amazon Bedrock services, capturing specific usage patterns of AI models by different business teams. These logs contain client-specific information, which for example can be used to enable organizations to implement capabilities such as charge-back models. This allows for accurate attribution of AI service usage to specific teams or departments, facilitating fair cost allocation and responsible resource utilization across the organization. These services work together to enhance security, optimize performance, and provide valuable insights for managing cross-account Amazon Bedrock access.

Conclusion

In this post, we explored the importance of securing and controlling network access to Amazon Bedrock capabilities within an organization’s AWS landing zone. We discussed the key business challenges, such as the need to protect sensitive information in Amazon Bedrock knowledge bases, limit access to AI models, and optimize cloud costs by monitoring and controlling Amazon Bedrock capabilities. To address these challenges, we outlined a multi-layered network solution that uses AWS networking services, including a VPC Lattice auth policy to restrict and monitor access to Amazon Bedrock capabilities. Try out this solution for your own use case, and share your feedback in the comments.


About the authors

Igniting innovation: How Experience AI is empowering teachers and students across Kenya

Post Syndicated from Victor Murithi original https://www.raspberrypi.org/blog/experience-ai-is-empowering-teachers-and-students-across-kenya/

This blog post is written by Victor Murithi, Communications and Media Consultant at Young Scientists Kenya, one of our global partners for Experience AI in Kenya.

When over 100 teachers from across Kenya gathered at Kangaru High School in Embu County for the Kenya Science and Engineering Fair Nationals in April, few anticipated just how transformative a two-day workshop could be. Delivered by the Experience AI Young Scientists Kenya (YSK) team, with support from the Raspberry Pi Foundation, the training sparked more than curiosity — it sparked a shift in mindset.

This wasn’t just about introducing new tools: it was about empowering teachers to confidently lead their students into an artificial intelligence (AI)-driven future.

Students in a classroom learn about Experience AI.

National reach and local impact

What began as a plan to train just 40 teachers quickly grew into something much bigger. By the time the workshop kicked off, 104 teachers from over 80 schools across 37 counties in Kenya, had registered and participated — nearly tripling the initial target.

This overwhelming interest confirmed a powerful insight: teachers are eager to understand AI, not only to better prepare their students for the future, but also for their own professional growth.

The workshop’s curriculum didn’t just focus on technical skills, it aimed to create confidence, clarity, and community among the attendees — key ingredients for successfully integrating AI into teaching and learning.

“Helping teachers move past their fear of AI and understand its potential is incredibly powerful. Because AI is the future, and through this training, we’re reaching the minds that will shape it,” explained Lucy Mwaniki, AI Community Trainer at YSK.

Practical skills, real outcomes

As part of the training, the attendees completed interactive worksheets, tested basic machine learning models, and sat a final comprehension test, something they found both validating and motivational.

“We were able to do the summative test… which turned out to be a very effective way of us understanding how in-depth and how well they grasped the knowledge,” says Lucy Mwaniki.

In one standout session, teachers collaboratively brainstormed ways AI could address national educational challenges. Ideas included models to assist students in selecting academic pathways within Kenya’s Competency Based Curriculum (CBC). Several teachers also successfully built working models, demonstrating the potential of applied learning. 

“It was a very eye-opening session… some of the teachers were able to create a very basic model, which was a wonderful experience for them,” Lucy Mwaniki explains. 

What made this training exceptional was its immediate applicability and long-term vision. By the end of two days, teachers weren’t just AI-aware — they were AI-ready, with many already starting to explore how AI tools could support entrepreneurship, lesson planning, and personalised learning pathways.

Students in a classroom setting; two of them are using a laptop to learn about AI.

Celebrating our achievements and impact 

At the close of the training, each teacher received a Certificate of Participation, recognising their commitment to professional development and their new capacity to bring AI into the classroom. The awarding of certificates added a sense of accomplishment and pride, reinforcing that teachers are key drivers of technological transformation in education.

And the impact of the training was measurable:

  • 95% of teachers agreed that the training increased their knowledge and confidence to teach AI concepts
  • 88% of teachers agreed that the training was high quality and useful for preparing them to teach the Experience AI lessons

But it doesn’t end there, as Vanessa Inziani, Head of Programs at YSK, explains, “Our commitment doesn’t end with the training — we continue to support educators with resources, mentorship, and follow-up to ensure success in delivering the program in the classroom.”

Looking ahead towards a promising AI journey

With the rapidly evolving digital landscape, AI is no longer a distant concept — it’s a present-day classroom necessity. Yet, introducing AI into schools isn’t just about technical literacy; it’s about confidence, clarity, and community and the approach the Young Scientist Kenya team and Experience AI delivered during the two-day training is anchored in this belief. 

As AI continues to shape the global education landscape, programs like Experience AI provide the bridge needed to equip teachers, inspire students, and future-proof education systems. The Kangaru High School session was not a one-off — it was a catalyst for systemic change. 

Experience AI is scaling. As it expands across Kenya and beyond, the benefits are clear:

  • Empowered educators who gain confidence and skills to integrate AI in their teaching
  • Future-ready students who grasp foundational AI concepts and their real-world applications
  • Sustainable impact as trained teachers go on to influence thousands of learners in their communities

The journey from fear to fluency starts with a single step, a willingness for us all to explore what’s possible. Together, we can equip educators, inspire students, and shape Kenya’s future, one AI-literate classroom at a time. 

About Experience AI

Experience AI is an AI literacy programme, co-developed by the Raspberry Pi Foundation and Google DeepMind, that teaches students aged 11 to 14 about AI and machine learning. Thanks to funding from Google.org, Young Scientists Kenya has partnered with the Raspberry Pi Foundation to provide free training to Kenyan educators, equipping them with the skills they need to effectively deliver the programme in their settings. They are one of two global partners working with the Raspberry Pi Foundation in Kenya.

You can find out more about the programme on our website: rpf.io/expai-ysk-blogpost

The post Igniting innovation: How Experience AI is empowering teachers and students across Kenya appeared first on Raspberry Pi Foundation.

AI security strategies from Amazon and the CIA: Insights from AWS Summit Washington, DC

Post Syndicated from Danielle Ruderman original https://aws.amazon.com/blogs/security/ai-security-strategies-from-amazon-and-the-cia-insights-from-aws-summit-washington-dc/

Speakers during AWS Summit Washington, DC 2025 on June 10, 2025.

At this year’s AWS Summit in Washington, DC, I had the privilege of moderating a fireside chat with Steve Schmidt, Amazon’s Chief Security Officer, and Lakshmi Raman, the CIA’s Chief Artificial Intelligence Officer. Our discussion explored how AI is transforming cybersecurity, threat response, and innovation across the public and private sectors. The conversation highlighted several key themes: how organizations can leverage AI to improve security outcomes, the rise of agentic AI and its impact on security, the importance of maintaining human oversight in AI systems, workforce development strategies, and practical approaches to implementing AI securely in enterprise environments. Below are a few excerpts from our conversation.

On leveraging AI to improve security outcomes

Steve Schmidt: “We’ve applied AI internally at Amazon in a couple of places that led to some significant benefits, including in the application security review process. By training our large language models internally on prior security reviews that we’ve done, it has allowed us to apply the knowledge and learning that our more senior staff have embodied in the documents that the LLM was trained on and expose that to our more junior staff. It really raises the bar on the absolute level of security that we can offer.”

Lakshmi Raman: “In the cybersecurity realm, we’re thinking about how AI helps us in our accreditation and authorization process, helping us ensure that the process to get systems accredited is going as quickly as possible, because the industry is moving so fast. Another area that we’re applying AI and machine learning is triaging data. We have vast amounts of data that comes in at an exponential rate, so we need to be able to go through it quickly so that we can surface insights. You can imagine a cybersecurity analyst who traditionally has gone through network data manually in order to think about blocking suspicious IP addresses or connections. Now there’s an opportunity to do all of that really efficiently and let the security analysts make the decision.”

On the rise of agentic AI and its implications for security

Steve Schmidt: “The biggest change we’re seeing right now in AI is the rise of agentic AI. The reason agentic AI is particularly interesting is that it brings with it a set of challenges about ensuring the software is taking actions within the context of the person who’s asking it…Think about that in the context of a government organization, where you have sets of information that are restricted to certain populations, there are classification decisions, access control limitations, and reasons that you can access certain data that have to be present before you can do so. Agentic AI brings opportunities—you can take actions using software automatically—but also challenges: how do we make sure that the software is doing exactly the right thing every single time, and more importantly, that we can prove what it did to stakeholders and regulators?”

Lakshmi Raman: “AI agents definitely have an opportunity to transform enterprise automation. Leveraging them to do complex multi-step workflows—to do tool calling across a variety of databases and other foundational tools—has tremendous potential, with a human as a crucial step to review what’s going on.”

On the importance of maintaining human oversight with AI

Lakshmi Raman: “In my world, I spend a lot of time thinking about how AI is impacting the workforce. One of the areas we’re looking at is the intersection between AI and our people. AI is able to speed up the processing and do automation, but at the end of the day, it’s really about who is taking on the risk, or deciding the intents and making the decisions. Whatever the machine output happens to be, really it’s about the human who’s deciding the level of oversight, the risk to take, and even whether to intervene.”

Steve Schmidt: “One thing that many people don’t realize about AI systems is that they’re nondeterministic. What nondeterminism means is you can ask an AI model the same question 100 times, and you will not get the same answer every time. So, having a human who can make a judgment about what the AI comes up with is critically important. We look at it this way: if you’re just asking a question and getting an answer, that may be one set of scrutiny that you have to get assistance. But if you’re going to take an action, you’ve got to be really sure the AI is correct. There has to be that skilled person that Lakshmi spoke about, at the end of the AI use process saying, ‘Yes, this is the right thing to do at this point in time with this context.’”

On building an AI-savvy security workforce

Steve Schmidt: “There’s a real problem in our industry: we don’t have enough security people. We simply can’t hire enough people with the right skills to do this job. What we’ve we found is that AI allows us to do a lot of the heavy lifting for the security staff, using tooling that used to have to be done by humans. Our staff is actually materially happier with their jobs if we remove a lot of that grunt work from them, which is super important. You want to keep the employees you have, so you give them tooling that helps them get the job done more efficiently, and they enjoy their job.”

Lakshmi Raman: “We’re looking for people who can live between the intersection of technology and social intelligence, people who can understand how those two areas can potentially interact around human behavior and how to think about future activities. When we’re thinking about analysts, for example, we’re thinking about people who have critical thinking skills, who can demonstrate analytic rigor, who can think multiple steps ahead with incomplete information. We’re also looking for people who have digital acumen with an understanding of cloud and cyber and AI, so that we have those technical skills in house. And finally, people who are interested in lifelong learning and curiosity, because threats change over the years. We need people who understand and are willing to learn about that.”

On advice for security leaders as AI accelerates

Steve Schmidt: “When you’re looking at making a decision, ask the person who’s bringing the information to you: ‘Why can’t AI do this?’ And if they don’t have an answer, ask ‘When will it be able to and under what condition?’ Move it into the now, the probable, the possible, and make it real for all of your staff all the time. If they’re not intentionally making that decision, they’re missing an opportunity.”

Lakshmi Raman: “You’ve got to get training out there for your users. We think of it at three different levels. First is our general workforce—which might be the most important user base—people who are sitting side by side with our AI practitioners and can help describe the workflows that need automation. Then we think about it for our practitioners, so they are keeping up with the latest. And then finally, our senior executives, who can think about how they can transform their organization with AI and generate that buy-in from the top level.”

AI is not just changing what we can do, but how we work. As Steve and Lakshmi emphasized, the most successful AI implementations will be those that thoughtfully balance automation with human oversight, focusing on use cases that deliver tangible value while managing risks appropriately. For security professionals, understanding both the technical and human dimensions of AI will be critical as we navigate this changing space.

Danielle Ruderman

Danielle Ruderman

Danielle is a Senior Manager for the AWS Worldwide Security Specialist Organization, where she leads a team that enables global CISOs and security leaders to better secure their cloud environments. Danielle is passionate about improving security by building company security culture that starts with employee engagement.

5 Things Security Leaders Need to Know About Agentic AI

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2025/06/09/5-things-security-leaders-need-to-know-about-agentic-ai/

5 Things Security Leaders Need to Know About Agentic AI

From writing assistance to intelligent summarization, generative AI has already transformed the way businesses work. But we’re now entering a new phase where AI doesn’t just generate content, but takes independent action on our behalf.

This next evolution is called ‘agentic AI’, and it’s moving fast. Amazon recently announced a dedicated R&D group focused on agentic systems. OpenAI is advancing its Codex Agent SDK to build more capable AI “workers.” And a growing number of businesses are actively experimenting with autonomous agents to handle everything from code generation to system orchestration.

While the potential is significant, so are the risks. These new systems bring fresh challenges for security teams, from unpredictable behavior and decision-making to new forms of supply chain exposure.

Here are five things every security leader needs to know right now.

1. Agentic AI is moving from research to reality

Unlike traditional generative AI, which responds to single prompts, agentic AI systems operate more autonomously, often over longer durations and with less human supervision. They can make decisions, learn from feedback, and complete multi-step tasks using reasoning and planning capabilities.

Some agents even have memory and goal-setting functions, enabling them to adapt to changing conditions and take initiative. This has huge implications for productivity but also opens the door to a new class of operational and security risks.

According to Forrester(1), agentic AI represents a shift “from words to actions,” with agents poised to become embedded across knowledge work, development, cloud operations, and customer-facing systems. Security teams must now consider not just what AI is generating, but what it’s doing.

2. Emerging use cases span development, robotics, and IT automation

Agentic AI has been surrounded by hype, but we’re already seeing practical use cases emerge across development, automation, and robotics.

  • Amazon’s new R&D group is focused on building AI agents for robotics and software orchestration, aiming to automate real-world tasks with physical and digital components.
  • OpenAI’s Codex Agent SDK is enabling developers to build custom agents that can interact with APIs, browse the web, and execute instructions without human involvement.
  • In enterprise IT, some early agentic tools are being used to generate and deploy scripts, configure systems, and resolve tickets across helpdesk platforms.

As these systems become more capable, they also become harder to predict. Agentic AI doesn’t just follow rules; it works toward outcomes. That makes it both valuable and volatile in enterprise environments.

3. The attack surface is expanding in new and subtle ways

One of the most critical risks that agentic AI introduces is decision unpredictability. These systems operate with a degree of autonomy, which means they can take action based on reasoning that isn’t always traceable or transparent. That creates blind spots for traditional controls.

Other risks include:

  • Prompt injection and manipulation, where attackers feed malicious instructions into agent workflows
  • Unintended lateral movement, especially when agents interact with APIs or third-party services
  • Supply chain exposure, as agents increasingly rely on external tools, plugins, and data sources to function

As noted at Infosecurity Europe, many of today’s AI threat models don’t yet account for agents that can generate, interpret, and act on instructions in dynamic environments. Traditional AppSec and identity controls will need to evolve to monitor not just access, but behavior over time.

4. Governance, observability, and containment are critical

As with earlier generations of AI, governance will define how successfully agentic systems can be adopted and secured.

Experts across MIT Sloan and Thoughtworks agree: organizations must rethink how they apply principles like least privilege, role-based access, and anomaly detection in an agentic context. That includes:

  • Observing how agents reason and make decisions
  • Restricting the actions they’re allowed to take (especially with sensitive data or infrastructure)
  • Implementing containment strategies that limit blast radius in case of failure or manipulation

Agent-based systems can’t be treated like static applications. Security teams need tools that provide ongoing insight into agent activity, and the ability to intervene when needed.

This is especially important when agents are integrated into security workflows themselves. If an agent is responsible for triaging alerts or executing playbooks, who’s accountable when it fails? And how do you audit its decisions?

5. Security teams have an opportunity to lead — but the window is narrow

We’re still in the early stages of agentic AI adoption, which gives security leaders a rare opportunity to influence how these systems are implemented from the outset. That includes building safe defaults, engaging with developers early, and applying threat modeling and testing before agents are deployed in production.

At Rapid7, we’ve already begun evaluating agent behavior through the lens of exposure, intent, and exploitability — the same principles that guide how we think about modern attack surfaces. Our goal is to help customers harness the speed and scale of AI without sacrificing visibility or control.

We’ve also introduced AI-powered application coverage in Exposure Command to help customers identify misconfigurations and application-layer weaknesses that could be exploited by or through autonomous tools.

Where security goes from here

Agentic AI represents the next wave of transformation. It’s not just generating output; it’s taking action. And while the business potential is huge, so is the responsibility to deploy it safely.

The attackers of 2025 are not just writing better phishing emails. They’re weaponizing automation, scaling social engineering, and skipping the learning curve. Security teams need to respond with visibility, control, and collaboration. Because when everyone has access to the same technology, it’s those who use it responsibly and defensively that come out ahead.

The time to prepare is now. Agentic AI is moving quickly…and it’s not waiting for security to catch up.


(1) Forrester (2025) With Agentic AI, Generative AI Is Evolving From Words to Actions. [online] Available at: https://reprint.forrester.com/reports/with-agentic-ai-generative-ai-is-evolving-from-words-to-actions-9c6cf2d9/index.html

India’s cyber leaders prepare for AI-driven threats

Post Syndicated from Rapid7 original https://blog.rapid7.com/2025/06/06/indias-cyber-leaders-prepare-for-ai-driven-threats/

India's cyber leaders prepare for AI-driven threats

As India’s economy rapidly digitizes, cybersecurity challenges are becoming increasingly complex. This May, Rapid7 launched our inaugural Global Security Day series across India, bringing together top security leaders in Mumbai, Delhi, and Bengaluru to address the most pressing cyber threats facing organizations in 2025.

Key insights that emerged

Across all three cities, several critical themes emerged that are shaping India’s cybersecurity landscape:

AI is No Longer Optional: Organizations recognize that AI has become essential for threat detection, exposure management, and SOC operations. The question is no longer whether to adopt AI, but how to implement it effectively.

Attack Surface Explosion: Cloud misconfigurations, insecure APIs, and identity misuse are driving today’s biggest risks. Organizations are struggling to maintain visibility and control across increasingly complex environments.

SOC Modernization is Urgent: Traditional Security Operations Centers need fundamental transformation, with automation and AI at their core to handle the volume of modern threats.

Talent Gap Challenges: Upskilling and reskilling initiatives are critical to closing the cybersecurity talent gap that’s affecting organizations globally, but particularly acutely in India’s booming tech sector.

Regulatory Evolution: India’s evolving cybersecurity regulatory landscape is shaping how organizations approach their security investments and strategy development.

A journey across India’s cyber capital cities

Our three-city roadshow, organized in collaboration with Information Security Media Group (ISMG), focused on the theme “2025 Cyber Threat Predictions: AI-Driven Attacks, Ransomware Evolution, and Expanding Attack Surface.” The response from India’s cybersecurity community was overwhelming, with 138 security leaders and delegates participating across all three cities.

Launching with impact in Mumbai (May 8)

Our Mumbai kickoff set the tone for the entire series, drawing 43 security leaders eager to dive into critical cybersecurity challenges. Rob Dooley, General Manager APJ, welcomed attendees before Regional CTO Robin Long delivered comprehensive insights on:

  • Global and Asia-Pacific threat landscape trends
  • The evolution of ransomware from double extortion to hybrid attacks
  • Expanding attack surfaces driven by cloud misconfigurations and insecure APIs
  • Next-generation defense strategies leveraging AI and continuous threat exposure management (CTEM)

The highlight was our fireside chat featuring Starlin Ponpandy, CISO of Orion Systems and Rapid7 customer, discussing ‘Building a New-Age SOC: Practical Applications of AI’. The conversation explored choosing the right SOC model, building effective teams, and navigating the complexities of AI trust and explainability.

The main focus of the Q&A was the evolving cyber threat landscape and how organizations can prepare for 2025’s AI-driven, increasingly complex attack environment.

The conversation was dominated by leaders sharing insights on the rise of AI-powered threats, the shift in ransomware tactics to double and hybrid extortion and the urgent need for proactive threat exposure management. Rapid7’s emphasis on real-time, AI-enabled defenses and automated risk management strategies sparked strong engagement.

Strategic dialogue in Delhi (May 13)

Our Delhi event brought together 43 delegates for candid, strategic discussions about 2025’s top cyber threats. Security leaders engaged in deep conversations about AI-powered detection and defense, proactive exposure management, and building resilient SOCs with automation.

The panel discussion on ‘Building a New-Age SOC’ addressed critical challenges including the cybersecurity talent gap and integrating security into DevOps workflows, a thought-provoking conversation examining identity-centric security models and the shift from traditional SOCs to Managed Detection and Response solutions.

Attendees posed incisive questions about upskilling teams in an AI-driven environment, managing tool sprawl, and operationalizing security by design – highlighting the sophisticated thinking of India’s cybersecurity leadership.

Tactical discussions in India’s Silicon Valley – Bengaluru (May 15)

Our Bengaluru finale drew the largest crowd with 52 delegates, including CISOs and cybersecurity executives from across South India. The discussions were highly tactical, focusing on:

  • Modernizing SOCs through AI-led threat detection
  • Countering double and triple extortion ransomware
  • Risk automation and secure cloud transformation

Veteran industry speaker Satish Kumar Dwibhashi joined Robin Long for discussions that reinforced a clear theme: security strategy must evolve in lockstep with attacker innovation.

Building for the future

The success of our India Security Days reflects not just the hunger for cybersecurity knowledge in the region, but also Rapid7’s commitment to supporting India’s digital transformation journey. We’re excited to announce that we’re expanding our presence with aGlobal Capability Center (GCC) in Pune, which will serve as a hub for innovation and home to teams across engineering, business support, and our Security Operations Center (SOC).

This initiative represents more than just business expansion – it’s about building cybersecurity capability and expertise right here in India, that will shape a secure digital future for organizations around the world.

The road ahead

The conversations, connections, and insights from our India Security Days have reinforced our belief that India’s cybersecurity community is among the most forward-thinking globally. The challenges are significant – from AI-powered attacks to evolving ransomware tactics – but so is the talent, innovation, and determination to address them.

As we look toward 2025 and beyond, events like these remind us that cybersecurity is ultimately about people: the security leaders making tough decisions, the practitioners implementing defenses, and the communities sharing knowledge and supporting each other.

Thank you to all the security leaders who joined us in Mumbai, Delhi, and Bengaluru. Your engagement, questions, and insights made these events truly impactful. We look forward to continuing these conversations and supporting India’s cybersecurity community as we navigate the challenges and opportunities ahead.

Interested in joining our growing team in India? Learn more about career opportunities at our new GCC in Pune.

Many voices, one community: Three themes from RSA Conference 2025

Post Syndicated from Anne Grahn original https://aws.amazon.com/blogs/security/many-voices-one-community-three-themes-from-rsa-conference-2025/

RSA Conference (RSAC) 2025 drew 730 speakers, 650 exhibitors, and 44,000 attendees from across the globe to the Moscone Center in San Francisco, California from April 28 through May 1.

The keynote lineup was eclectic, with 37 presentations featuring speakers ranging from NBA Hall of Famer Earvin “Magic” Johnson to public and private-sector luminaries such as former US National Cyber Director Chris Inglis, U.S. Secretary of Homeland Security Kristi Noem, and cryptography experts Tal Rabin, Whitfield Diffie, and Adi Shamir.

Topics aligned with this year’s conference theme, “Many Voices. One Community,” and focused on the security industry’s shared drive to foresee risks, counter threats, and embrace new challenges.

Three themes caught our attention: agentic AI, cryptography, and public-private collaboration.

Agentic AI

The potential of agentic AI to augment human decision-making was a common thread among conversations at the conference. Numerous sessions touched on the topic, and the desire of attendees to understand the technology and learn how to balance its risks and opportunities was clear.

Separating hype from reality

An AI agent is a software program that can interact with its environment (as detailed in Figure 1), collect data, and use the data to perform self-determined tasks to meet predetermined goals.

Figure 1: Generative AI agents

Figure 1: Generative AI agents

Agentic systems offer a fundamentally different approach compared to traditional software, particularly in their ability to handle complex, dynamic, and domain-specific challenges. While traditional systems rely on rule-based automation and structured data, agentic systems use large language models (LLMs)—a subset of generative AI—to operate autonomously. Agents can learn from interactions with users, and make nuanced, context-aware decisions while keeping human analysts in the loop.

Numerous RSAC speakers alluded to AI agents as the next frontier in enterprise transformation. Gartner® predicts that: “By 2028, 33% of enterprise software applications will include agentic AI, up from less than 1% in 2024,” and “at least 15% of day-to-day work decisions will be made autonomously through agentic AI, up from zero percent in 2024.”

However, as organizations build AI agents, understanding the concerns that come with them is critical.

“Agentic AI presents tremendous opportunities to deliver business value and innovative security outcomes. Production deployments require a balance between its capabilities, and robust security and trust mechanisms.”
—Hart Rossman, Global Services Security Vice President at AWS

In the RSAC keynote session The Five Most Dangerous New Attack Techniques…and What to Do for Each, Rob Lee, Chief of Research and Head of Faculty at SANS Institute noted that while security teams are embracing AI to amplify productivity, threat actors are doing the same. He pointed to MIT research that shows adversarial agent systems executing attack sequences are 47 times faster than human operators, with a 93 percent success rate in privilege escalation paths.

Safeguarding GenAI & Agentic Apps, Top 10 Risks in 2025, a half-day Open Worldwide Application Security Project (OWASP) event, focused on helping attendees distinguish real threats from hype. OWASP Gen AI Security Project team members and industry experts reviewed the 2025 OWASP Top 10 List for LLM and GenAI (shown in Figure 2), and introduced Agentic AI—Threats and Mitigations—the first in a series of guides from the OWASP Agentic Security Initiative (ASI) to provide a threat-model-based reference of emerging agentic threats and mitigations. Content feedback can be submitted to ASI in advance of the guide’s next release.

Figure 2: 2025 OWASP Top 10 for LLM Applications

Figure 2: 2025 OWASP Top 10 for LLM Applications

Agentic AI wins Cybersecurity Startup Accelerator

The second annual AWS and CrowdStrike Cybersecurity Startup Accelerator, in collaboration with the NVIDIA Inception program, took place during RSAC. A panel of judges—including George Kurtz, Founder and CEO of CrowdStrike, CJ Moses, Chief Information Security Officer at Amazon, and David Reber Jr., Chief Security Officer at NVIDIA—evaluated startups on innovation, market relevance, and go-to-market potential. Terra Security, a provider of agentic AI-powered, continuous web application penetration testing, was selected from a group of 10 finalists who pitched live. Two runners-up, Kenzo Security and Rig Security, were also recognized for their standout approaches to agentic AI-driven security.

Addressing AI risks

The need to consider your security posture when assessing overall AI readiness was emphasized throughout the conference. A defense-in-depth architecture can help mitigate risks with multiple layers of protection across both traditional and AI software components. Innovative solutions such as AI red teaming, AI behavioral sandboxing, and advanced tracing and evaluation of generative AI agents can enhance your security strategy with a proactive approach to securing AI.

Visit the following resources to help design, build, and operate AI systems: DevsecOps Revolution: Unleashing Generative AI for Automated Excellence, AWS generative AI security, responsible AI, and the Amazon AGI Labs Blog.

Cryptography

Encryption was another key topic. The FIDO Alliance hosted a half-day seminar that focused on developments in the global movement to passwordless technology such as passkeys—cryptographic keys designed to replace passwords by combining the power of public key cryptography with biometric authentication.

In Dude, Where’s My Password? The Challenges of Getting to Passwordless, Andy Ozment, Chief Technology Risk Officer and Executive Vice President at Capital One noted that 88 percent of data compromised in basic web application attacks reported in 2024 involved stolen credentials. Ozment pointed out that “going passwordless” through a combination of X.509 device certificates and FIDO2 passkeys presented Capital One with an opportunity to nearly eliminate entire classes of threats (as detailed in Figure 3), while increasing the quality of user experience.

Figure 3: Using passkeys to reduce risk while advancing user experience

Figure 3: Using passkeys to reduce risk while advancing user experience

Along the way, Ozment said, Capital One’s journey to passwordless was enabled by its transition from on-premises technology to going “all-in” on the public cloud. Watch the recording of his session or view the slides to learn more.

Post-quantum encryption

The state of post-quantum encryption was detailed in the popular Cryptographer’s Panel, moderated by Tal Rabin, Senior Principal Applied Scientist at AWS.

Panelist Vinod Vaikuntanathan, Professor at MIT underscored the impact of the quantum-resistant algorithm standardization process (Figure 4) started by the National Institute of Standards and Technology (NIST) in 2016. “We now have two public key encryption algorithms, and three new digital signature algorithms that are standardized,” he pointed out.

Figure 4: Post-quantum encryption algorithms

Figure 4: Post-quantum encryption algorithms

The panelists agreed that even though quantum computers aren’t here yet, the time to deploy these algorithms is now. NIST recommends phasing out existing encryption methods by 2030 in its Transition to Post-Quantum Cryptography Standards report. However, Vaikuntanathan and Adi Shamir, the “s” in the Rivest–Shamir–Adleman (RSA) public-key cryptosystem, advise organizations to take a hybrid approach that combines classic encryption algorithms such as RSA or Elliptic-curve Diffie–Hellman (ECDH) with post-quantum algorithms such as Module-Lattice-based Key Encapsulation Mechanism (ML-KEM). This approach, which is used by AWS and recommended by The European Commission, offers protection against both current and future threats.

RSAC Award for Excellence in the Field of Mathematics

Dr. Shai Halevi, Senior Principal Applied Scientist at AWS, was presented with the Award for Excellence in the Field of Mathematics for remarkable contributions to many areas of cryptography, including fundamental theory, advanced cryptographic primitives, secure multi-party computations, homomorphic encryption, and cryptographic code obfuscation.

Figure 5: Dr. Shai Halevi receives RSAC award for Excellence in the Field of Mathematics

Figure 5: Dr. Shai Halevi receives RSAC Award for Excellence in the Field of Mathematics

End-to-end encryption

Concerns about the recent US government group chat leak were also raised during the discussion. Public-key cryptography pioneer Whitfield Diffie noted that the use of an encrypted consumer messaging app to communicate classified information broke archiving laws. Because some commercial tools use 256-bit Advanced Encryption Standard (AES) encryption, which is “good enough” to protect communications, he predicted an increase in the use of consumer applications to protect sensitive information in unapproved ways.

The Cybersecurity and Infrastructure Security Agency (CISA) and the Federal Bureau of Investigation (FBI) recently advised individuals and organizations to start using encrypted messaging apps. However, as the role of these applications in business communication expands, it’s important not to lose sight of recordkeeping and compliance obligations. Organizations should consider solutions that offer administrative controls and data retention capabilities along with encryption.

AWS Wickr, for example, is a messaging and collaboration service that protects messaging, calling, file sharing, screen sharing, and location sharing with 256-bit end-to-end encryption. The data retention and administrative controls that it provides help customers meet regulatory requirements and manage user and device data remotely.

Wickr is Department of Defense Cloud Computing Security Requirements Guide Impact Level 5 (DoD CC SRG IL5) and Federal Risk and Authorization Management Program (FedRAMP) High authorized in the AWS GovCloud (US-West) Region. It also meets compliance programs and standards such as Health Insurance Portability and Accountability Act (HIPAA) eligibility, International Organization for Standardization (ISO) 27001, and System and Organization Controls (SOC) 1, 2, and 3.

Visit the AWS News Blog and the AWS Security Blog to learn about AWS passkey multi-factor authentication, how AWS is migrating to post quantum cryptography (PQC), and how we can help you implement a layered encryption strategy for your organization.

Public-private collaboration

Numerous sessions underlined the importance of collaboration to strengthening security. In his keynote, Johnson called attention to a lesson he learned on the basketball court—his peers made him stronger. “Larry Bird made me a better basketball player,” he said, relating his experience to the need for security teams to assist and learn from each other.

In Making America Safe Again Through Cyber Defense, Kristi Noem, U.S. Secretary of Homeland Security equated cybersecurity with national security, and insisted that building on public-private partnerships is “incredibly important.” “Our goal,” she said, “is to use our maximum effect of cooperation to make sure that we’re going after bad actors.”

After assuring attendees that CISA will continue to be America’s cyber defense agency, she urged congress to reauthorize the Cybersecurity Information Sharing Act of 2015. The law, which is set to expire in September, incentivizes businesses to share threat indicators with the Department of Homeland Security (DHS) and helps make sure that both the federal government and companies can take collaborative steps to address threats.

Panelists at an offsite threat intelligence discussion reiterated the ability of private industry to supplement government security capabilities. Adam Meyers, Senior VP, Counter Adversary Operations at CrowdStrike pointed out that technology companies often have more data and signals than governments. The CrowdStrike Falcon solution, he said, processes over 6 trillion events per day, and 55 million events per second at peak. This volume facilitates the detection of threat patterns that might otherwise go unnoticed.

Similarly, Moses noted that the size and scale of AWS infrastructure gives us unique visibility into internet traffic. Our global network of sensors and associated disruption tools observe over 700 million threat interactions every day, out of which 450 million can be classified as malicious. Internal threat intelligence tools such as MadPot, our sophisticated global honeypot system, produce high-fidelity findings (pieces of relevant information) that can be used to drive proactive intelligence sharing, and reduce investigative workloads.

“We’ll work together in order to be able to put a bow on a case and hand it to the FBI and DOJ, such that they don’t have to expend a great amount of resources in order to go forward and try to figure things out that we already know.” —CJ Moses, Chief Information Security Officer and VP of Security Engineering at Amazon

An example of this is the disruption of the cybercriminal group known as Anonymous Sudan. The group was responsible for tens of thousands of distributed denial-of-service (DDoS) attacks against critical infrastructure, corporate networks, and government agencies. With the help of tools like MadPot, AWS experts were able to identify the hosting provider infrastructure that the group used to launch the DDos attacks, and work with providers to disrupt them. Akamai SIRT, Cloudflare, CrowdStrike, DigitalOcean, Flashpoint, Google, Microsoft, PayPal, SpyCloud, and other private sector entities also assisted law enforcement, leading to the indictment of two Anonymous Sudan leaders.

The value of combined perspectives

RSA Conference 2025 might be over, but the learning continues. Additional highlights that include the west stage keynotes, the Innovation Sandbox, and dozens of insightful sessions on topics such as the changing role of the CISO, women in cyber, and of course—cloud security—are available on demand.

If there’s one key takeaway, it’s a collective sense of transition. As we explore the benefits and risks of emerging AI technologies, encryption strategies, and information sharing, it’s important to remember that we cannot effectively combat threats in isolation. Security is a collective endeavor; only by working together can we adapt to evolving challenges and build cyber resilience.

For more information about cloud security, register to join AWS, Google Cloud, and Microsoft online at the SANS 2025 Cloud Security Exchange on August 21.

Anne Grahn

Anne Grahn

Anne is a Senior Worldwide Security GTM Specialist at AWS, based in Chicago. She has 15 years of experience in the security industry and focuses on effectively communicating cybersecurity risk. She maintains a Certified Information Systems Security Professional (CISSP) certification.

Introducing AI Attack Coverage in Exposure Command: Secure what traditional AppSec Tools miss

Post Syndicated from Michael Chroney original https://blog.rapid7.com/2025/06/03/introducing-ai-attack-coverage-in-exposure-command-secure-what-traditional-appsec-tools-miss/

Introducing AI Attack Coverage in Exposure Command: Secure what traditional AppSec Tools miss

The rise of GenAI-powered applications – from internal copilots to customer-facing chatbots – is changing how businesses operate. While these tools drive innovation, they also introduce a fast moving, often invisible layer of risk.

Most traditional AppSec tools were never built to handle the unique threats of conversational AI interfaces. As attackers get savvier, security teams need the right kind of coverage.

That’s why we’re excited to introduce AI Attack Coverage in Exposure Command and InsightAppSec.

This release brings purpose built protection for AI driven applications into your existing AppSec workflows, so you can uncover vulnerabilities that legacy tools miss – and stop AI specific threats before they become business problems.

A new class of risk requires a new kind of coverage

As organizations embrace GenAI, they’re also expanding their attack surface – often without realizing it. LLMs (large language models) and AI integrations create new opportunities for attackers to exploit vulnerabilities like:

  • Prompt injection: Tricking the model into revealing sensitive data or bypassing security controls.
  • Plugin abuse: Misusing connected tools through AI interfaces.
  • Data leakage: Inadvertent exposure of sensitive information in responses.

The problem? These aren’t issues most scanners can detect, and manual reviews don’t scale. AI Attack Coverage addresses this gap head-on with capabilities designed to tackle the evolving threat landscape.

Built to secure what matters most

AI Attack Coverage in Exposure Command introduces a suite of enhancements that work seamlessly within your existing DevSecOps pipelines:

  • Smarter scanning for smarter apps: Our enhanced R7Crawler interacts with LLMs and chatbots in real-world ways – uncovering vulnerabilities traditional scanners can’t see.
  • Purpose built LLM testing: With 6 new attack modules, comprising 25+ new attack techniques, that will target six of the OWASP Top 10 for LLMs, we help you find prompt injection, improper output handling, and more.
  • AI aware validation: Reduce false positives with intelligent validation powered by AWS Nova Pro, so teams can focus on what’s real and actionable.
  • Developer first remediation: Features like Attack Replay and CI/CD integrations help teams fix faster – without slowing down releases​.
Introducing AI Attack Coverage in Exposure Command: Secure what traditional AppSec Tools miss

Complete visibility, from code to cloud

Exposure Command doesn’t stop at the app layer. With integrated telemetry from InsightCloudSec, you also get:

  • Full-stack visibility into where GenAI services live across your environment.
  • Automated enforcement of security best practices for AI/ML environments.
  • Unified context to prioritize what’s truly risky in your hybrid estate. ​

Get started with AI Attack Coverage

If you’re building with AI – or thinking about it – now’s the time to make sure your security strategy keeps up. AI Attack Coverage gives your team the visibility, context, and control to manage risk in a world where apps are getting smarter, and attackers are more adept at exploiting them.

Whether you’re an AppSec engineer, a risk leader, or a CISO trying to future-proof your security posture, Exposure Command brings it all together.

Learn More About Rapid7’s Exposure Command

Confidently identify and prioritize exposures from endpoint to cloud with full attack surface visibility and threat-aware risk context.

Analyze media content using AWS AI services

Post Syndicated from Jack Bradham original https://aws.amazon.com/blogs/architecture/analyze-media-content-using-aws-ai-services/

Organizations managing large audio and video archives face significant challenges in extracting value from their media content. Consider a radio network with thousands of broadcast hours across multiple stations and the challenges they face to efficiently verify ad placements, identify interview segments, and analyze programming patterns.

In this post, we demonstrate how you can automatically transform unstructured media files into searchable, analyzable content. By combining Amazon Transcribe, Amazon Bedrock, Amazon QuickSight, and Amazon Q, organizations can achieve the following:

  • Process and transcribe media files upon upload
  • Identify commercials, interviews, and program segments
  • Extract insights using foundation models (FMs)
  • Create a searchable knowledge base
  • Generate rich visualizations for decision-making
  • Enable natural language queries across their media archive
  • Visualize complex information with intuitive graphics

In the following sections, we explore how these AWS services work together to help organizations unlock the full potential of their media content, whether for advertising compliance, content analysis, or discovering specific segments within thousands of hours of recordings.

Solution overview

This solution provides an event-driven media analysis pipeline that transforms how you manage and extract value from your content:

  • Streamline content management – Automatically process media files the moment they’re uploaded, saving time and reducing manual work
  • Unlock deeper insights – Generate accurate transcriptions that capture not just words, but the full context of your content—including speakers, timing, and key moments
  • Harness AI – Automatically extract meaningful insights and uncover hidden patterns in your media without extensive manual review
  • Build a searchable knowledge base – Turn scattered media files into a discoverable catalog that your entire team can use
  • Build a customizable interface – Create a customizable UI to search the catalog
  • Create powerful visualizations – Bring your insights to life with intuitive visualizations that make complex information immediately understandable

The following diagram illustrates our architecture.

Media Analysis Architecture

This event-driven architecture automatically processes and analyzes multimedia content using AWS services. The workflow consists of the following steps:

  1. A user uploads media files to an Amazon Simple Storage Service (Amazon S3) bucket. A “New Media” event triggers the first AWS Step Functions workflow. This workflow handles the initial cataloging based on values in the file name and launches the transcription process.
  2. Amazon Transcribe converts the audio into accurate, readable text. The transcribed content is securely saved to an S3 bucket for further analysis. A “Transcription Complete” event triggers the next step.
  3. A second Step Functions workflow processes the transcription. Using predefined prompts, Amazon Bedrock analyzes the transcripts to extract meaningful information. Key insights extracted from the transcript are stored in an S3 data lake.
  4. The processed results are organized systematically, structured by date (year/month/day) and tagged with relevant attributes. This organized data enables natural language queries through Amazon Q when used as a knowledge base, interactive visualizations using QuickSight, and straightforward content discovery and analysis.
  5. Amazon Athena serves as the data exploration tool to query the data lake. Athena is used as the data source in QuickSight, which turns complex data into clear, compelling visuals.

This architecture automatically transforms raw media content into searchable, analyzable data while maintaining an organized hierarchy for efficient access and analysis. The event-driven design provides automatic processing of new content as it arrives, and the combination of AWS AI services enables deep content understanding and insight extraction. Each AWS service plays a crucial role in transforming your media content:

  • Amazon Bedrock – Reviews content after transcription for insights and entity extraction:
    • Uses advanced FMs to analyze transcripts
    • Identifies commercials, interviews, and program segments
    • Extracts meaningful insights from content
  • Amazon EventBridge – Triggers actions in the cataloging workflow:
    • Monitors for new media files and completed transcriptions
    • Automatically triggers Step Functions workflows
  • AWS Lambda – Handles custom code actions needed in the workflow:
    • Facilitates interaction with Amazon Bedrock
    • Executes custom prompts on transcripts
    • Enables flexible, scalable processing
  • Amazon Q – Serves as the frontend and Retrieval Augmented Generation (RAG) engine:
    • Addresses enterprise generative AI needs by providing a turnkey solution with built-in security features like single sign-on (SSO) integration and responsible AI governance policies
    • Allows businesses to quickly deploy AI assistance while maintaining compliance, data privacy, and security standards
    • Enables natural language queries across the media archive
    • Links results to the source media files
    • Provides conversational access to content
  • Amazon QuickSight – Turns insights in beautiful visualization for better consumption:
    • Creates interactive dashboards and visualizations
    • Displays comprehensive media analytics
    • Helps track advertising, programming, and content patterns
  • Amazon S3 – Stores assets and the catalog:
    • Securely stores raw media files, transcripts, and processed data
    • Automatically triggers processing when new content is uploaded
  • AWS Step Functions – Orchestrates the entire content processing workflow:
    • Manages transcription and AI analysis steps
    • Provides robust error handling and automatic retries
  • Amazon Transcribe – Converts speech to accurate, readable text:
    • Identifies speakers and timestamps
    • Provides accurate transcriptions of audio content

Security considerations

Although this post focuses on the technical implementation of media content analysis, it’s important to acknowledge that production deployments should include comprehensive security measures:

  • Data storage security (Amazon S3):
    • Enable server-side encryption using AWS Key Management Service (AWS KMS) keys
    • Apply bucket policies restricting access to authorized principals only
    • Enable Amazon S3 Block Public Access at account and bucket levels
    • Enable versioning for data recovery
    • Implement lifecycle policies for data retention
    • Enable S3 access logging
    • Use presigned URLs for temporary access
  • Identity and Access Management (IAM):
    • Create dedicated service roles with minimum required permissions for:
      • Step Functions execution
      • Amazon Transcribe jobs
      • Amazon Bedrock API calls
      • Athena queries
    • Implement role-based access control
    • Regularly rotate credentials
    • Enable multi-factor authentication (MFA) for all users
    • Use AWS Organizations for multi-account management
  • Network security:
    • Deploy virtual private cloud (VPC) endpoints for:
      • Amazon S3
      • Athena
      • QuickSight
    • Implement network access control lists (ACLs) and security groups
    • Enable VPC Flow Logs
    • Use AWS PrivateLink where applicable
    • Configure route tables to control traffic flow
  • Data encryption:
    • Implement AWS KMS encryption for S3 objects
    • Use TLS 1.2+ for all API communications
    • Enable automatic key rotation in AWS KMS
    • Implement envelope encryption for sensitive data
  • Monitoring and detection:
    • Enable AWS CloudTrail for API activity logging
    • Configure Amazon GuardDuty for threat detection
    • Set up Amazon CloudWatch:
      • Metrics for service health
      • Alarms for security events
      • Log groups for application logs
    • Enable S3 server access logging
    • Configure VPC Flow Logs
  • Access controls:
    • Implement fine-grained access controls for:
      • Amazon Bedrock model access
      • Athena query permissions
      • QuickSight dashboard sharing
    • Conduct regular access reviews

Additionally, compliance requirements and data governance policies might impact how you implement this solution in your environment.

These security considerations are crucial but beyond the scope of this post. We recommend consulting AWS security best practices and working with your security team to implement appropriate measures for your specific use case. For more information on AWS security best practices, refer to Best Practices for Security, Identity, & Compliance.

The following sections walk you through setting up each component of the architecture to help you transform raw media into actionable insights.

Prerequisites

The following are the prerequisites to follow along this post:

Create S3 buckets

For this solution, we create three distinct buckets to support the media analytics workflow:

  • Raw media bucket for incoming files
  • Transcription outputs bucket
  • Processed insights bucket

For instructions on creating buckets, refer to Creating a general purpose bucket.

Configure EventBridge

You can enable event notifications on the raw media bucket to trigger your automated workflow through EventBridge. Establish your automation backbone by monitoring S3 bucket activities. When new media arrives or transcription completes, EventBridge will trigger the appropriate workflow, providing continuous processing. For further instructions, refer to Creating rules that react to events in Amazon EventBridge.

The following are two example triggers that can be used to filter events and trigger Step Functions workflows. The following is an example filter for new media files:

{
  "source": ["aws.s3"],
  "detail-type": ["Object Created"],
  "detail": {
    "bucket": {
      "name": ["rawinputbucket"]
    }
  }
}

The following is an example filter for new transcripts added to the data lake:

{
  "source": ["aws.s3"],
  "detail-type": ["Object Created"],
  "detail": {
    "bucket": {
      "name": ["business-data-lake"]
    },
    "object": {
      "key": [{
        "suffix": ".transcription"
      }]
    }
  }
}

Create Step Functions workflows

We design the orchestration layer with two key workflows. The first handles media intake and transcription, and the second manages AI analysis. Each workflow includes safeguards for potential failures and retry mechanisms. For further instructions, refer to Learn how to get started with Step Functions.

The following diagram shows an example of processing new media uploads for indexing and transcription.

Media Analysis - Step Function Example

The following diagram shows an example of the Step Functions workflow that analyzes the transcription.

Set up Amazon Transcribe

To create an Amazon Transcribe job, you need permissions to do so. You can implement a speech-to-text conversion with powerful features like language detection, speaker identification, and custom vocabulary support to provide accurate transcription of your media content. For further instructions, refer to How Amazon Transcribe works.

Configure Amazon Bedrock

You can power your AI analysis engine by setting up precise prompts that extract meaningful insights. Amazon Bedrock processes transcripts to identify key segments, speakers, and topics, transforming raw text into structured data. For instructions, refer to Design a prompt.

The following is a sample prompt:

You will be reviewing a radio transcription to identify advertisements and extract relevant details. Your task is to analyze the provided transcript and output the results in a specific JSON format based on a given schema.
Please follow these steps to complete the task:
1. Carefully read through the entire transcript.
2. Identify all advertisements within the transcript. Look for clear indicators such as product mentions, promotional language, or transitions from regular content to commercial content.
3. For each advertisement you identify, determine the following information:
    - Company: The name of the company being advertised
    - Start time: The timestamp in the transcript where the ad begins
    - End time: The timestamp in the transcript where the ad ends
    - Product: The specific product or service being advertised
4. Format your findings into a JSON object that follows the provided schema. Each advertisement should be a separate object within an array.
5. Ensure these fields in your response are provided for each advertisement.. All are required fields: company, starttime, endtime, product. 
6. Use precise timestamps for start and end times. If exact times are not available, make a best estimate based on the transcript's context.
7. If a particular field is unclear or not explicitly mentioned in the transcript, you may use "Unknown" as the value.
8. Only respond with json and nothing else. Do not provide comments or explain your answer. 
9. Surround the JSON response with standard ```json markers
Here's an example of how your output should be formatted:
{
"advertisements": [
        {
            "company": "TechGadgets Inc.",
            "starttime": "00:05:30",
            "endtime": "00:06:15",
            "product": "SmartHome Hub"
        },
        {
            "company": "FreshFoods Market",
            "starttime": "00:15:45",
            "endtime": "00:16:30",
            "product": "Organic Produce Delivery Service"
        }
    ]
}
Do not add any fields that are not specified in the schema, and ensure all required fields are present for each advertisement.

Create a structured data lake

We create a hierarchical data organization strategy that enables efficient access and analysis. You can use AWS Glue crawlers to automatically discover and catalog your media metadata. For instructions, refer to Using crawlers to populate the Data Catalog. Configure Athena tables to enable SQL-based querying of your media insights:

CREATE OR REPLACE VIEW "commercials_view" AS 
SELECT
  metadata.market market
, metadata.station_call station_call
, metadata.format_type format_type
, CAST(metadata.timestamp AS timestamp) timestamp
, ads.company adCompany
, ads.product adProduct
, ads.starttime
, ads.endtime
FROM
  (commercials
CROSS JOIN UNNEST(advertisements) t (ads))

Set Up Amazon Q

You can enable natural language interaction with your media archive using Amazon Q Business. Configure the knowledge base and metadata to make your content searchable and accessible through conversational queries. Use the processed insights S3 buckets to configure the knowledge base. For instructions, refer to Getting started with Amazon Q Business.

The following screenshot shows example conversations with an AI assistant.

Build QuickSight dashboards

With QuickSight, you can create visual analytics that bring your data to life. Connect to Athena views to display advertising patterns, content analysis, and performance metrics in interactive dashboards. For more information, refer to Tutorial: Create an Amazon QuickSight dashboard.

The following screenshots are a few examples of dashboards created for a fictitious radio station as part of our use case.

Validate and optimize your media analytics solution

After you implement your media analytics architecture, follow these critical steps to achieve robust performance and alignment with your organization’s needs. First, configure a comprehensive testing approach. Imagine you’re preparing to launch your media analysis solution. Your testing journey begins with accuracy validation:

  • Compare transcription outputs against original media
  • Verify AI-generated insights for precision
  • Use representative sample sets from your content library

You start by taking a recently processed radio show and comparing its transcription against the original broadcast. Your team meticulously reviews the AI-generated insights, checking if key moments like ad transitions or interview segments are correctly identified. To make sure your system works across all content types, you select diverse samples from your library—perhaps a morning talk show, an evening news segment, and a weekend sports broadcast. Next, you delve into performance benchmarking:

  • Measure processing time for different media types
  • Evaluate resource utilization across AWS services
  • Identify potential bottlenecks in the workflow

Time how long it takes to process different types of media files, from short commercial segments to lengthy program recordings. As you watch how your AWS services respond under various loads, you can monitor resource consumption patterns. This helps you identify processing bottlenecks—for instance, you might discover that certain file types take longer to transcribe or that concurrent processing needs optimization. Finally, you put yourself in your users’ shoes for a thorough user experience assessment:

  • Test natural language queries with Amazon Q
  • Validate search result relevance
  • Gather feedback from potential end-users

Team members can interact with Amazon Q, asking questions they would naturally pose when searching for specific content. For example, you can test whether searching for “interviews about climate change last week” returns relevant results. Gathering feedback from potential users—perhaps a content manager with different needs than a compliance officer—provides invaluable insights. Their real-world experiences guide your refinements and make sure the system serves its intended purpose. This comprehensive testing approach, combining structured evaluation with real-world scenarios, sets the stage for a robust and user-friendly media analysis solution. As your media analysis solution moves from initial deployment to production, optimizing its performance becomes crucial for both cost-efficiency and user satisfaction. A radio network processing thousands of hours of content weekly might find that even small improvements in transcription accuracy or processing speed can lead to significant cost savings and better content discoverability. Similarly, a marketing team analyzing ad placements across multiple stations needs precise insights to make data-driven decisions about advertising effectiveness. With these business imperatives in mind, consider the following configuration optimization strategies:

  • Transcription refinement:
    • Adjust language models for domain-specific terminology
    • Fine-tune speaker identification settings
    • Implement custom vocabularies for improved accuracy
  • AI insight generation:
    • Refine prompts for more targeted analysis
    • Experiment with different AI models
    • Align extraction parameters with business objectives
  • Scalability considerations:
    • Test workflow performance with increasing media volumes
    • Implement appropriate auto scaling configurations
    • Monitor cost-effectiveness of your architecture
  • Continuous improvement:
    • Establish regular review cycles
    • Track key performance metrics
    • Iterate on your solution based on real-world usage

We recommend starting with a pilot implementation and gradually expanding your media analytics capabilities.

Clean up

To avoid incurring ongoing charges, clean up the resources you created as part of this solution:

  1. Delete QuickSight resources:
    1. Delete dashboards created for media analytics.
    2. Delete the datasets connected to Athena.
    3. If no longer needed, delete the QuickSight Enterprise subscription.
  2. Delete S3 buckets:
    1. Empty and delete the raw media bucket, transcription outputs bucket, and processed insights bucket.
  3. Remove EventBridge rules:
    1. Delete the rules created for monitoring S3 bucket activities.
    2. Remove targets associated with these rules.
  4. Delete Step Functions workflows:
    1. Delete the media intake and transcription workflow.
    2. Delete the AI analysis workflow.
  5. Remove Lambda functions:
    1. Delete Lambda functions created for interaction with Amazon Bedrock.
    2. Remove associated IAM roles and policies.
  6. Clean up data lake components:
    1. Delete Athena views and tables.
    2. Remove AWS Glue crawlers and databases.
    3. Delete stored query results.
  7. Remove Amazon Q configurations:
    1. Delete knowledge bases created.
    2. Remove custom configurations.
  8. Remove Amazon Bedrock settings:
    1. Remove custom prompts.
    2. Disable access to FMs if no longer needed.
  9. Delete Amazon Transcribe settings:
    1. Remove custom vocabularies.
    2. Delete stored transcription jobs.
  10. Remove IAM resources:
    1. Delete custom IAM roles created for this solution.
    2. Remove associated IAM policies.
  11. Complete additional cleanup:
    1. Delete CloudWatch Logs groups associated with Lambda functions.
    2. Remove CloudWatch alarms or metrics created for monitoring.
    3. Delete saved queries in Athena.

Common use cases

Organizations in different sectors can use this architecture to unlock value from their audio and video content. You can adapt this solution to meet your specific needs, such as managing broadcast media, corporate communications, educational materials, and more. Let’s explore how different industries might apply this technology:

  • Media and broadcasting:
    • Track advertising compliance
    • Verify media placement accuracy
    • Analyze broadcast content at scale
  • Corporate and enterprise:
    • Convert meeting recordings into searchable knowledge bases
    • Identify key decisions and action items
    • Enhance organizational knowledge management
  • Education and training:
    • Create comprehensive, topic-based course catalogs
    • Index training materials for quick retrieval
    • Support continuous learning initiatives
  • Legal services:
    • Generate precise, timestamped transcripts
    • Develop searchable legal proceeding archives
    • Improve document review efficiency
  • Healthcare:
    • Extract critical medical insights from consultations
    • Categorize patient interaction data
    • Support clinical documentation processes
  • Government and public sector:
    • Build comprehensive public meeting archives
    • Implement automated topic categorization
    • Enhance transparency and accessibility
  • Customer service:
    • Analyze call recordings for quality improvement
    • Identify service trends and customer pain points
    • Drive continuous customer experience enhancement

This media analytics architecture demonstrates notable versatility. By using AI, organizations can transform raw audio and video content into structured, meaningful insights that drive decision-making across industries.

Conclusion

In this post, we demonstrated how to use AWS services to convert unstructured media content into actionable intelligence. By combining Amazon Transcribe, Amazon Bedrock, QuickSight, and Amazon Q, you can create a scalable, automated solution for media analysis that adapts to your organizational needs.

This solution offers the following key architectural advantages:

  • Automated media file processing at scale
  • AI-powered insight generation
  • Natural language search capabilities
  • Interactive decision-making visualizations
  • Flexible, maintainable infrastructure

Organizations can now convert content into searchable knowledge, extract insights automatically, develop data-driven content strategies, and enhance operational efficiency through automation.

As audio and video content generation continues to accelerate, the ability to efficiently process and extract value becomes increasingly critical. This architecture provides a robust foundation for current needs while remaining adaptable to future technological innovations.

We invite you to explore how this media analytics solution can address your organization’s unique challenges. Consider your specific use cases and unlock the insights waiting to be discovered in your media archives.


About the authors