Tag Archives: artificial intelligence

Bridging the divide: Connecting global communities with Experience AI

Post Syndicated from Katherine Leadbetter original https://www.raspberrypi.org/blog/bridging-the-divide-connecting-global-communities-with-experience-ai/

From smart devices to workplace tools, AI is becoming part of everyday life and a major part of how people are thinking about the future — raising big questions about access, skills, and readiness.

As governments around the world create AI strategies for the decade ahead, many are seeing an urgent need to address the large gap between how AI tools are already impacting jobs and people’s lives, and making sure young people have the chance to gain the skills and knowledge to keep up with this rapid pace of technological change. This gap is larger still when it comes to opportunities for educationally underserved communities.
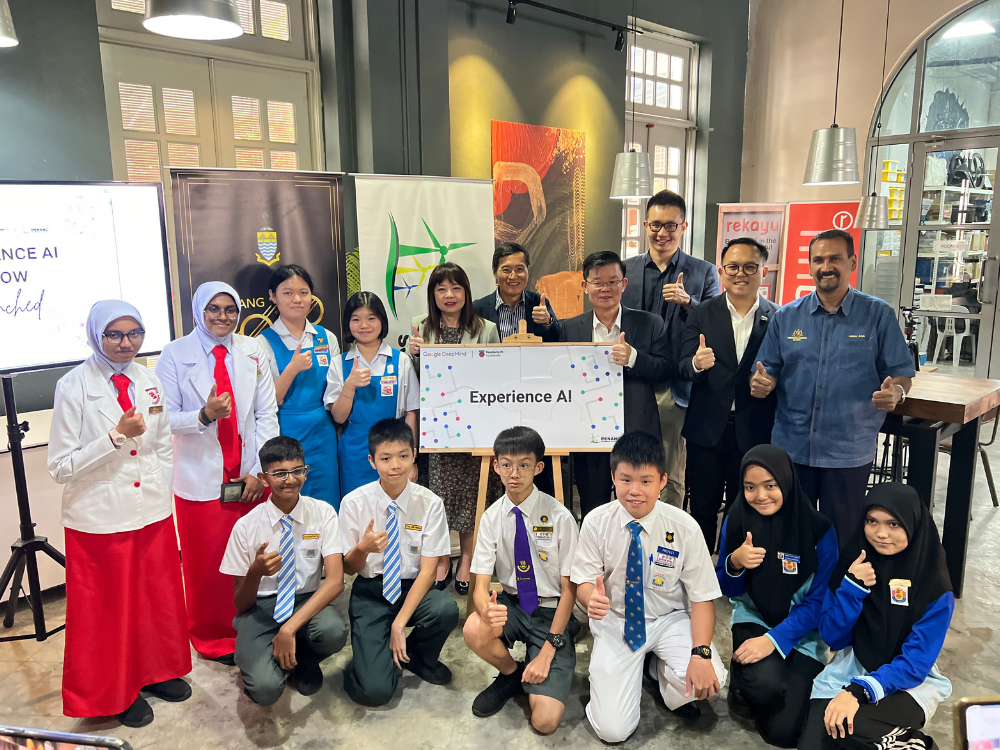
A group of students and educators holding an Experience AI poster.

That’s why we’re excited to share how Experience AI, our AI literacy programme, is helping organisations around the world create these much-needed opportunities for young people.

The value of a global network

Experience AI was co-developed in 2022 by us and industry experts at Google DeepMind with a clear mission: to equip teachers with free, accessible, easy-to-use classroom resources that build AI literacy from the ground up. The programme offers a suite of materials to help students understand real-world applications of AI, the basics of machine learning, and the ethical considerations around these technologies.
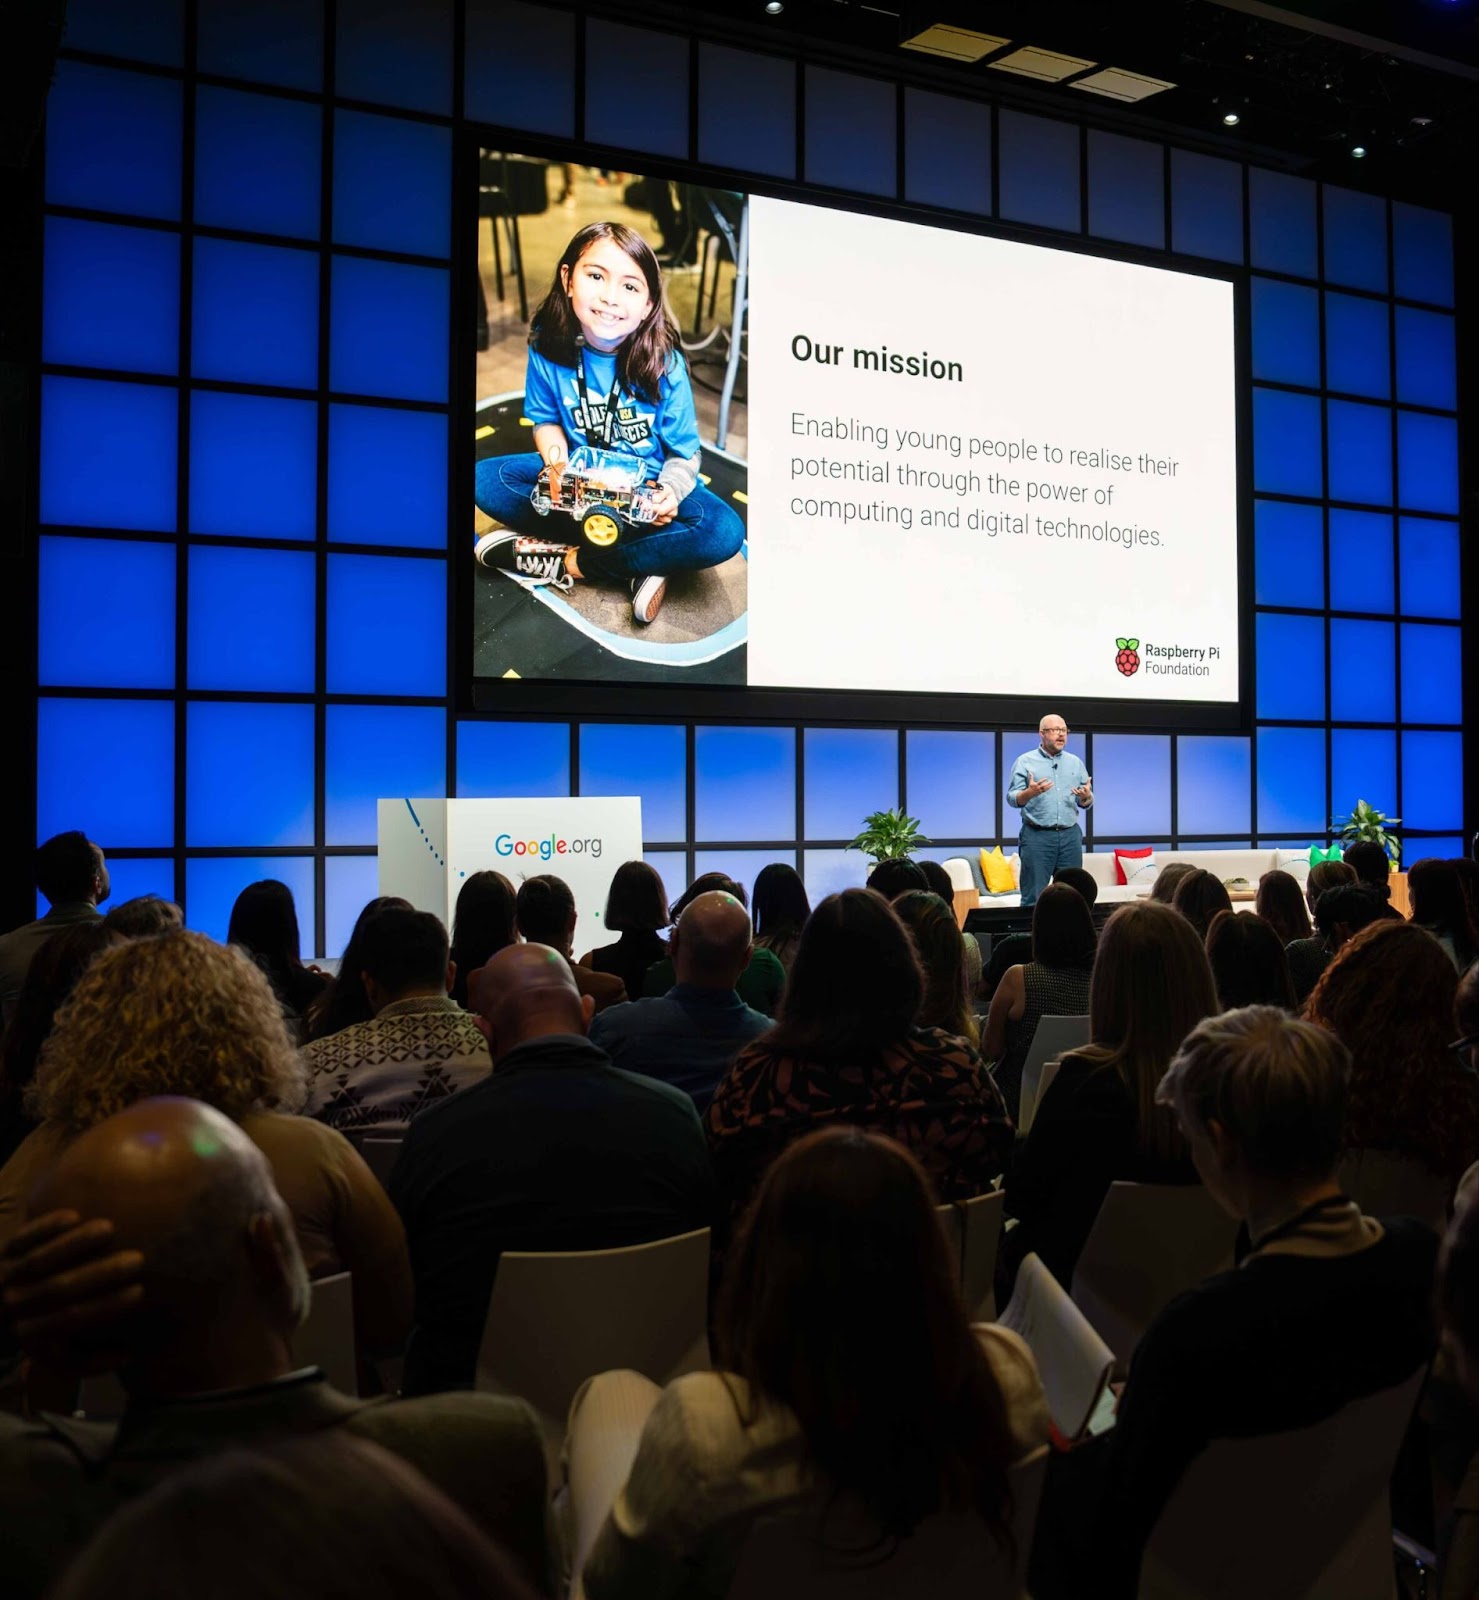
A picture of Philip Colligan delivering a talk.

In 2023, we started building an international Experience AI network by collaborating with a group of our existing educational partners. We saw a huge amount of interest and received very positive feedback, and through our partnerships we reached an estimated one million young people. In late 2024, with support from Google.org, we tripled the size of our Experience AI partner network to 21, with new organisations joining from across Europe, the Middle East, and Africa. In this way, we aim to reach an additional 2.3 million young people by December 2026, helping them to gain the knowledge and skills to confidently engage with AI in an ever-changing world.

Each partner in the Experience AI network is a unique educational organisation looking to create lasting social change. Through their local knowledge and networks, we can present Experience AI to educators and students in a way that is engaging and relevant for local communities. 
A group of students participating in an Experience AI session.

Partners help us to adapt and translate our resources, all while making sure that the core pedagogy and design principles of Experience AI are preserved. Just as importantly, these organisations train thousands of teachers on how to use the materials, providing educators with free support. With their work, they reach communities that otherwise may have never had the opportunity to learn about AI.

We asked some of our partners to share their insights on the impact Experience AI is having on the teachers and young people in their communities.

Building communities

The Latvian Safer Internet Centre (LSIC), an initiative of our partner, the Latvian Internet Association (LIA), is dedicated to helping young people protect themselves online, and to preparing them for a fast-changing digital economy. As an Experience AI partner, they aim to train 850 teachers and support 43,000 students to build a strong foundation in AI literacy through the programme.

“We hope to spark a cultural shift in how AI is […] taught in Latvian schools. Our goal is for AI literacy to become a natural part of digital competence education, not an optional extra.”
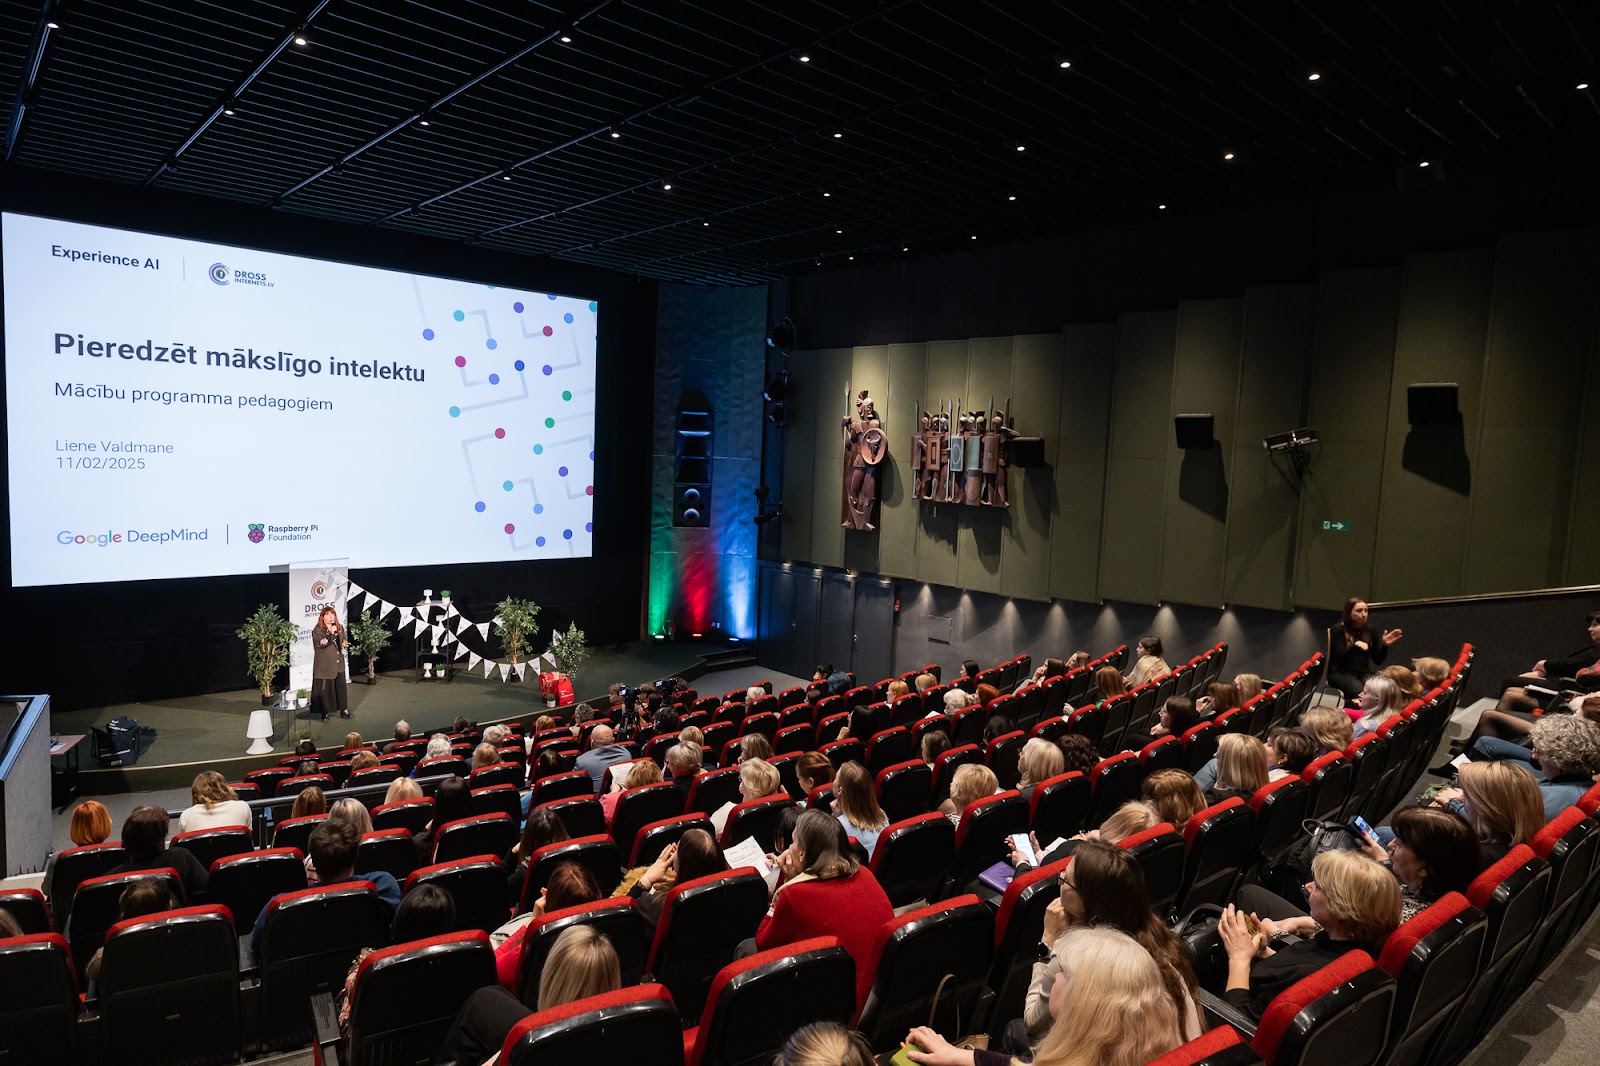
A woman is delivering a presentation about Experience AI.

Based in Riga, the team is travelling to 18 different regions across Latvia to bring in-person professional development to teachers, including those in rural communities far from major cities. By meeting teachers where they are, the LIA are creating invaluable networks for learning and support between communities. Through hands-on training, they are also supporting teachers to bring Experience AI into their own classroom, creating examples which are suited for their learners.

“We chose an in-person training model because it fosters a more collaborative and engaging environment, especially for teachers who are new to AI. Many educators, particularly those who are less confident with digital tools, benefit from direct interaction, real-time discussions, and the chance to ask questions in a supportive setting.” 

As an Experience AI partner, the Latvian Internet Association is not just delivering content but working to strengthen digital competency across the country and ensure that no teacher or student is left behind in Latvia’s AI journey. 

One teacher shares: “The classroom training was truly valuable: it gave us the chance to exchange ideas and reflect on our diverse experiences. Hearing different perspectives was enriching, and I’m glad we’re shaping the future of our schools together.”

“AI is for everyone”

EdCamp Ukraine’s mission is to unite educators and help them to grow. Operating from their main base in Kharkiv, near the Eastern border and the frontline of the ongoing war in Ukraine, they see AI as both a tool for new technological breakthroughs and as something that can help build a fairer, more efficient, and resilient society.

“We firmly believe AI should not only be an object of study — it must become a tool for amplifying human potential. AI should also not be a privilege, but a resource for everyone. We believe the Experience AI programme can truly transform education from the bottom up.”
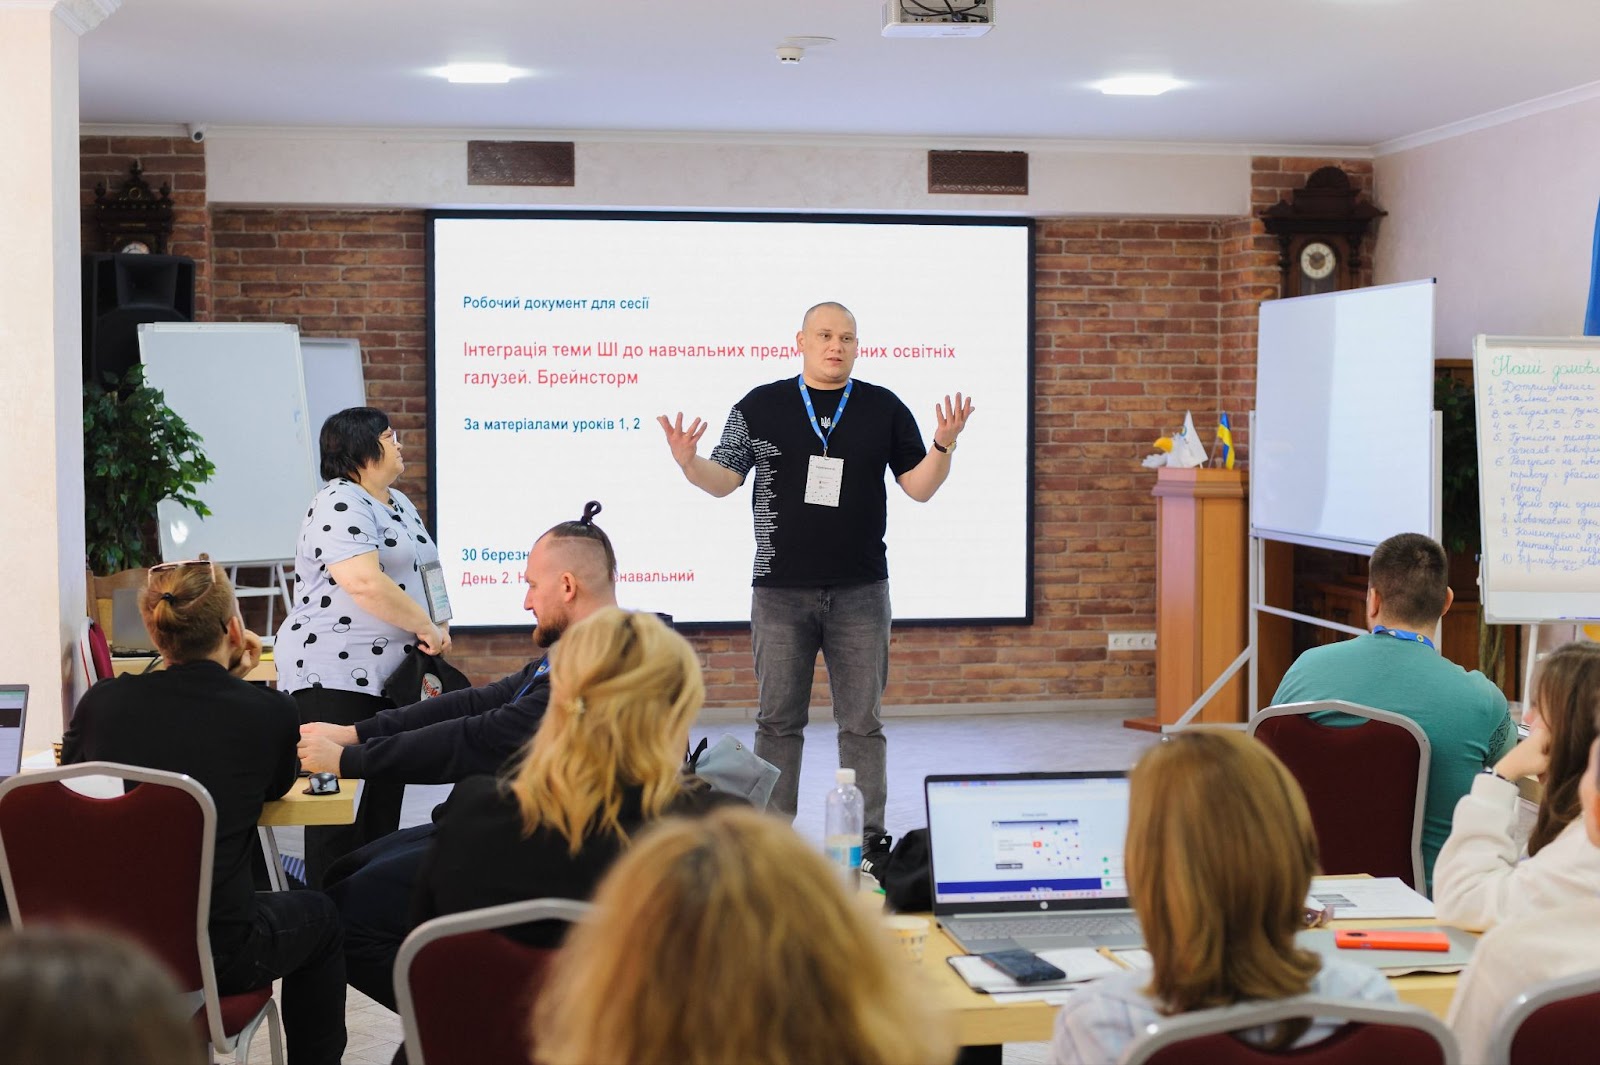
A man is delivering a presentation about Experience AI to a group of educators.

Within their community of 50,000 teachers, EdCamp Ukraine ensures that every educator, regardless of their living conditions or where they work, can access high-quality, relevant, and accessible support. For the organisation, the ongoing situation in Ukraine means being flexible with planning, preparing for a range of different outcomes, and being ready to pivot delivery to different locations or to an online setting when needed. These same considerations apply to EdCamp Ukraine’s teacher community, who need to be ready to adapt their lessons for any scenario.

“Recognising these war-related challenges helps us see the bigger picture and always have contingency plans in place. We think ahead and develop flexible scenarios.”
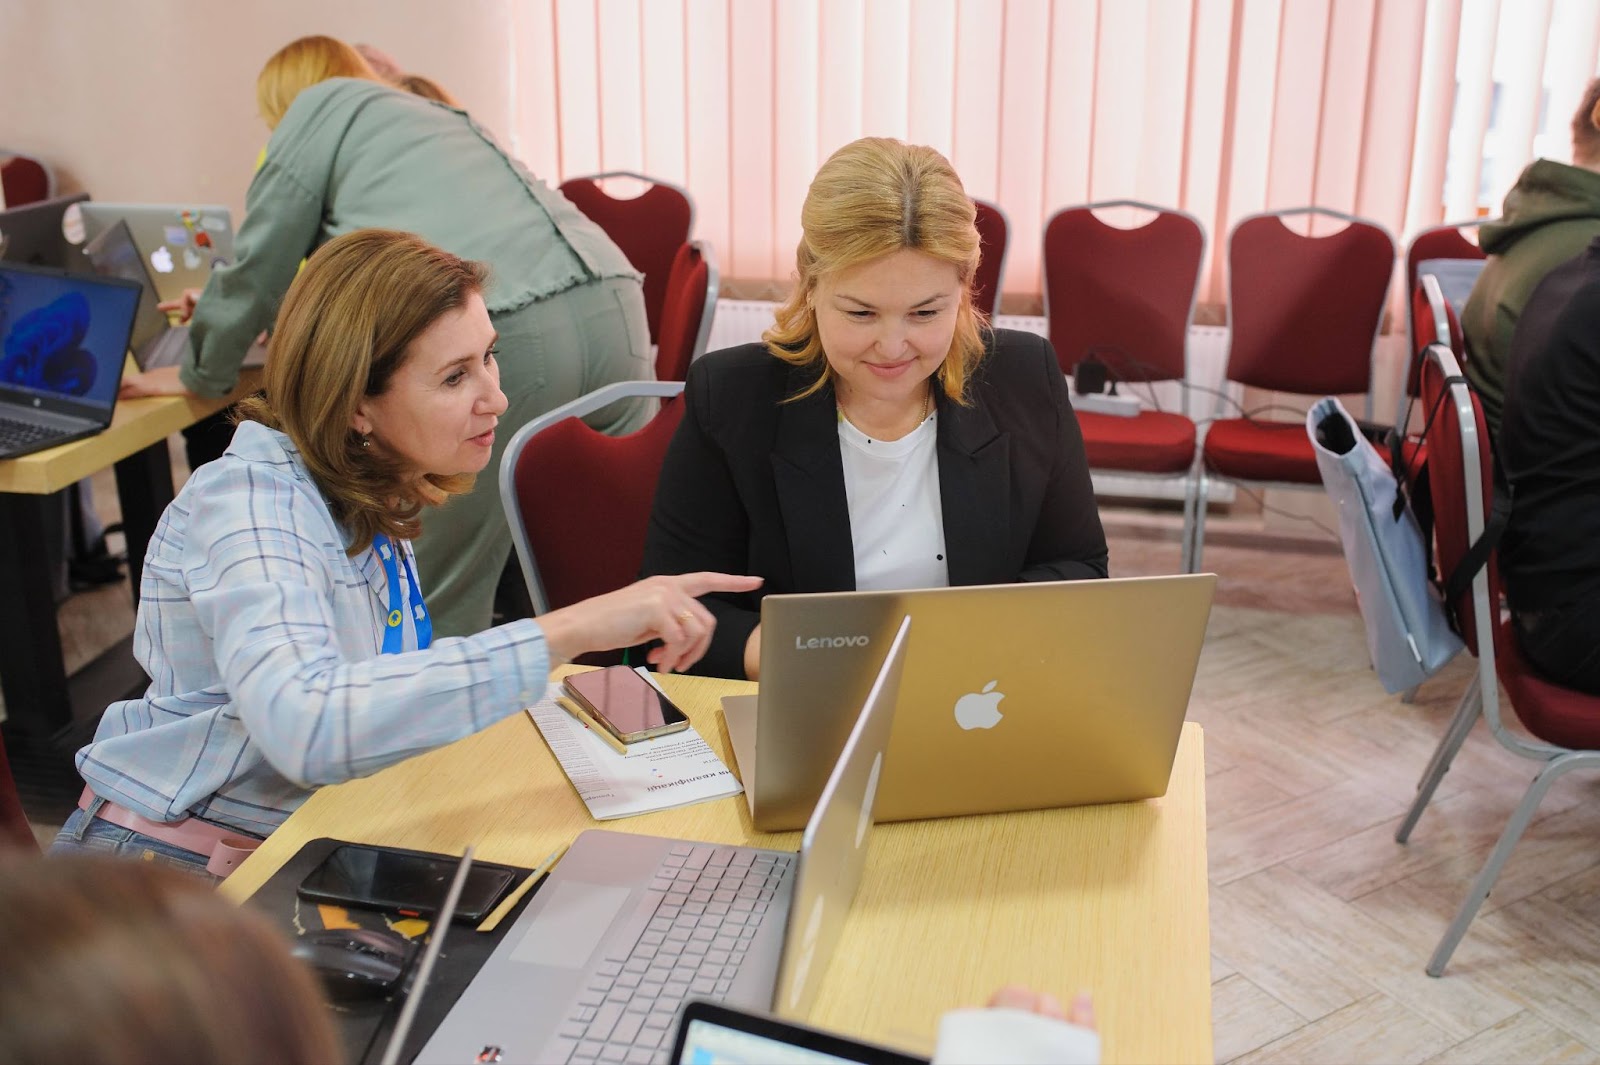
Two educators looking at a laptop screen.

This year, the team piloted Experience AI through their community of trainers, who, when they’re not training, are busy teaching in the classroom. Teacher Yuliia shared how her students valued the opportunity to be creators, rather than just users of technology:

“One student, who is an active AI user, kept silent during the lesson. I thought he wasn’t interested, but during the reflection he shared a lot of positive feedback and expressed his gratitude. Other students said it was important that they weren’t just told about AI — they were using it, creating images, and working with apps.”
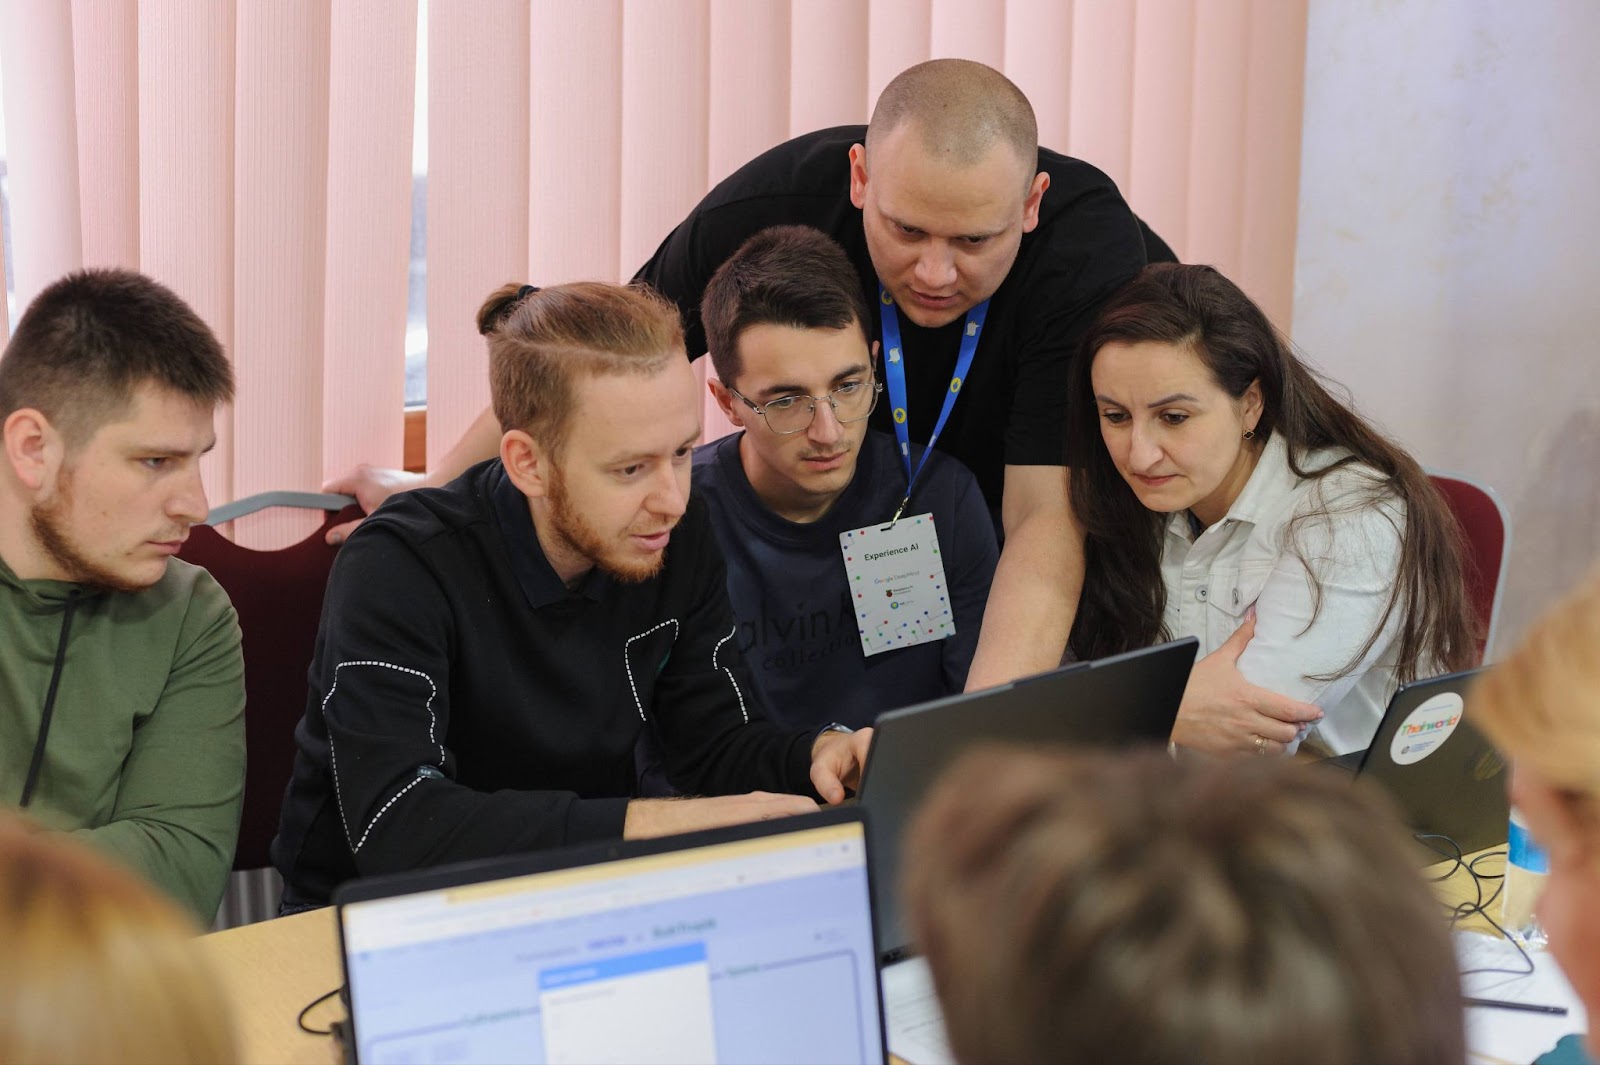
A group of educators looking at a laptop screen.

EdCamp Ukraine plans to roll out training for Ukrainian teachers this autumn, reaching 2,000 teachers and 40,000 young people by the end of next year. 

More countries, more classrooms 

Two new partners in Nigeria are about to join the Experience AI network, and there are many more organisations in more countries coming soon. As our partner network continues to grow, we are excited to reach more communities and give more young people around the world the chance to build AI literacy skills and knowledge. 

You can find out more about Experience AI on the website. If your organisation is interested in partnering with us to deliver Experience AI, please register your interest and we will let you know about opportunities to work with us.

The post Bridging the divide: Connecting global communities with Experience AI appeared first on Raspberry Pi Foundation.

Introducing Claude 4 in Amazon Bedrock, the most powerful models for coding from Anthropic

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/claude-opus-4-anthropics-most-powerful-model-for-coding-is-now-in-amazon-bedrock/

Anthropic launched the next generation of Claude models today—Opus 4 and Sonnet 4—designed for coding, advanced reasoning, and the support of the next generation of capable, autonomous AI agents. Both models are now generally available in Amazon Bedrock, giving developers immediate access to both the model’s advanced reasoning and agentic capabilities.

Amazon Bedrock expands your AI choices with Anthropic’s most advanced models, giving you the freedom to build transformative applications with enterprise-grade security and responsible AI controls. Both models extend what’s possible with AI systems by improving task planning, tool use, and agent steerability.

With Opus 4’s advanced intelligence, you can build agents that handle long-running, high-context tasks like refactoring large codebases, synthesizing research, or coordinating cross-functional enterprise operations. Sonnet 4 is optimized for efficiency at scale, making it a strong fit as a subagent or for high-volume tasks like code reviews, bug fixes, and production-grade content generation.

When building with generative AI, many developers work on long-horizon tasks. These workflows require deep, sustained reasoning, often involving multistep processes, planning across large contexts, and synthesizing diverse inputs over extended timeframes. Good examples of these workflows are developer AI agents that help you to refactor or transform large projects. Existing models may respond quickly and fluently, but maintaining coherence and context over time—especially in areas like coding, research, or enterprise workflows—can still be challenging.

Claude Opus 4
Claude Opus 4 is the most advanced model to date from Anthropic, designed for building sophisticated AI agents that can reason, plan, and execute complex tasks with minimal oversight. Anthropic benchmarks show it is the best coding model available on the market today. It excels in software development scenarios where extended context, deep reasoning, and adaptive execution are critical. Developers can use Opus 4 to write and refactor code across entire projects, manage full-stack architectures, or design agentic systems that break down high-level goals into executable steps. It demonstrates strong performance on coding and agent-focused benchmarks like SWE-bench and TAU-bench, making it a natural choice for building agents that handle multistep development workflows. For example, Opus 4 can analyze technical documentation, plan a software implementation, write the required code, and iteratively refine it—while tracking requirements and architectural context throughout the process.

Claude Sonnet 4
Claude Sonnet 4 complements Opus 4 by balancing performance, responsiveness, and cost, making it well-suited for high-volume production workloads. It’s optimized for everyday development tasks with enhanced performance, such as powering code reviews, implementing bug fixes, and new feature development with immediate feedback loops. It can also power production-ready AI assistants for near real-time applications. Sonnet 4 is a drop-in replacement from Claude Sonnet 3.7. In multi-agent systems, Sonnet 4 performs well as a task-specific subagent—handling responsibilities like targeted code reviews, search and retrieval, or isolated feature development within a broader pipeline. You can also use Sonnet 4 to manage continuous integration and delivery (CI/CD) pipelines, perform bug triage, or integrate APIs, all while maintaining high throughput and developer-aligned output.

Opus 4 and Sonnet 4 are hybrid reasoning models offering two modes: near-instant responses and extended thinking for deeper reasoning. You can choose near-instant responses for interactive applications, or enable extended thinking when a request benefits from deeper analysis and planning. Thinking is especially useful for long-context reasoning tasks in areas like software engineering, math, or scientific research. By configuring the model’s thinking budget—for example, by setting a maximum token count—you can tune the tradeoff between latency and answer depth to fit your workload.

How to get started
To see Opus 4 or Sonnet 4 in action, enable the new model in your AWS account. Then, you can start coding using the Bedrock Converse API with model IDanthropic.claude-opus-4-20250514-v1:0 for Opus 4 and anthropic.claude-sonnet-4-20250514-v1:0 for Sonnet 4. We recommend using the Converse API, because it provides a consistent API that works with all Amazon Bedrock models that support messages. This means you can write code one time and use it with different models.

For example, let’s imagine I write an agent to review code before merging changes in a code repository. I write the following code that uses the Bedrock Converse API to send a system and user prompts. Then, the agent consumes the streamed result.

private let modelId = "us.anthropic.claude-sonnet-4-20250514-v1:0"

// Define the system prompt that instructs Claude how to respond
let systemPrompt = """
You are a senior iOS developer with deep expertise in Swift, especially Swift 6 concurrency. Your job is to perform a code review focused on identifying concurrency-related edge cases, potential race conditions, and misuse of Swift concurrency primitives such as Task, TaskGroup, Sendable, @MainActor, and @preconcurrency.

You should review the code carefully and flag any patterns or logic that may cause unexpected behavior in concurrent environments, such as accessing shared mutable state without proper isolation, incorrect actor usage, or non-Sendable types crossing concurrency boundaries.

Explain your reasoning in precise technical terms, and provide recommendations to improve safety, predictability, and correctness. When appropriate, suggest concrete code changes or refactorings using idiomatic Swift 6
"""
let system: BedrockRuntimeClientTypes.SystemContentBlock = .text(systemPrompt)

// Create the user message with text prompt and image
let userPrompt = """
Can you review the following Swift code for concurrency issues? Let me know what could go wrong and how to fix it.
"""
let prompt: BedrockRuntimeClientTypes.ContentBlock = .text(userPrompt)

// Create the user message with both text and image content
let userMessage = BedrockRuntimeClientTypes.Message(
    content: [prompt],
    role: .user
)

// Initialize the messages array with the user message
var messages: [BedrockRuntimeClientTypes.Message] = []
messages.append(userMessage)

// Configure the inference parameters
let inferenceConfig: BedrockRuntimeClientTypes.InferenceConfiguration = .init(maxTokens: 4096, temperature: 0.0)

// Create the input for the Converse API with streaming
let input = ConverseStreamInput(inferenceConfig: inferenceConfig, messages: messages, modelId: modelId, system: [system])

// Make the streaming request
do {
    // Process the stream
    let response = try await bedrockClient.converseStream(input: input)

    // Iterate through the stream events
    for try await event in stream {
        switch event {
        case .messagestart:
            print("AI-assistant started to stream"")

        case let .contentblockdelta(deltaEvent):
            // Handle text content as it arrives
            if case let .text(text) = deltaEvent.delta {
                self.streamedResponse + = text
                print(text, termination: "")
            }

        case .messagestop:
            print("\n\nStream ended")
            // Create a complete assistant message from the streamed response
            let assistantMessage = BedrockRuntimeClientTypes.Message(
                content: [.text(self.streamedResponse)],
                role: .assistant
            )
            messages.append(assistantMessage)

        default:
            break
        }
    }

To help you get started, my colleague Dennis maintains a broad range of code examples for multiple use cases and a variety of programming languages.

Available today in Amazon Bedrock
This release gives developers immediate access in Amazon Bedrock, a fully managed, serverless service, to the next generation of Claude models developed by Anthropic. Whether you’re already building with Claude in Amazon Bedrock or just getting started, this seamless access makes it faster to experiment, prototype, and scale with cutting-edge foundation models—without managing infrastructure or complex integrations.

Claude Opus 4 is available in the following AWS Regions in North America: US East (Ohio, N. Virginia) and US West (Oregon). Claude Sonnet 4 is available not only in AWS Regions in North America but also in APAC, and Europe: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Hyderabad, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), and Europe (Spain). You can access the two models through cross-Region inference. Cross-Region inference helps to automatically select the optimal AWS Region within your geography to process your inference request.

Opus 4 tackles your most challenging development tasks, while Sonnet 4 excels at routine work with its optimal balance of speed and capability.

Learn more about the pricing and how to use these new models in Amazon Bedrock today!

— seb

Empower financial analytics by creating structured knowledge bases using Amazon Bedrock and Amazon Redshift

Post Syndicated from Nita Shah original https://aws.amazon.com/blogs/big-data/empower-financial-analytics-by-creating-structured-knowledge-bases-using-amazon-bedrock-and-amazon-redshift/

Traditionally, financial data analysis could require deep SQL expertise and database knowledge. Now with Amazon Bedrock Knowledge Bases integration with structured data, you can use simple, natural language prompts to query complex financial datasets. By combining the AI capabilities of Amazon Bedrock with an Amazon Redshift data warehouse, individuals with varied levels of technical expertise can quickly generate valuable insights, making sure that data-driven decision-making is no longer limited to those with specialized programming skills.

With the support for structured data retrieval using Amazon Bedrock Knowledge Bases, you can now use natural language querying to retrieve structured data from your data sources, such as Amazon Redshift. This enables applications to seamlessly integrate natural language processing capabilities on structured data through simple API calls. Developers can rapidly implement sophisticated data querying features without complex coding—just connect to the API endpoints and let users explore financial data using plain English. From customer portals to internal dashboards and mobile apps, this API-driven approach makes enterprise-grade data analysis accessible to everyone in your organization. Using structured data from a Redshift data warehouse, you can efficiently and quickly build generative AI applications for tasks such as text generation, sentiment analysis, or data translation.

In this post, we showcase how financial planners, advisors, or bankers can now ask questions in natural language, such as, “Give me the name of the customer with the highest number of accounts?” or “Give me details of all accounts for a specific customer.” These prompts will receive precise data from the customer databases for accounts, investments, loans, and transactions. Amazon Bedrock Knowledge Bases automatically translates these natural language queries into optimized SQL statements, thereby accelerating time to insight, enabling faster discoveries and efficient decision-making.

Solution overview

To illustrate the new Amazon Bedrock Knowledge Bases integration with structured data in Amazon Redshift, we will build a conversational AI-powered assistant for financial assistance that is designed to help answer financial inquiries, like “Who has the most accounts?” or “Give details of the customer with the highest loan amount.”

We will build a solution using sample financial datasets and set up Amazon Redshift as the knowledge base. Users and applications will be able to access this information using natural language prompts.

The following diagram provides an overview of the solution.

For building and running this solution, the steps include:

  1. Load sample financial datasets.
  2. Enable Amazon Bedrock large language model (LLM) access for Amazon Nova Pro.
  3. Create an Amazon Bedrock knowledge base referencing structured data in Amazon Redshift.
  4. Ask queries and get responses in natural language.

To implement the solution, we use a sample financial dataset that is for demonstration purposes only. The same implementation approach can be adapted to your specific datasets and use cases.

Download the SQL script to run the implementation steps in Amazon Redshift Query Editor V2. If you’re using another SQL editor, you can copy and paste the SQL queries either from this post or from the downloaded notebook.

Prerequisites

Make sure your meet the following prerequisites:

  1. Have an AWS account.
  2. Create an Amazon Redshift Serverless workgroup or provisioned cluster. For setup instructions, see Creating a workgroup with a namespace or Create a sample Amazon Redshift database, respectively. The Amazon Bedrock integration feature is supported in both Amazon Redshift provisioned and serverless.
  3. Create an AWS Identity and Access Management (IAM) role. For instructions, see Creating or updating an IAM role for Amazon Redshift ML integration with Amazon Bedrock.
  4. Associate the IAM role to a Redshift instance.
  5. Set up the required permissions for Amazon Bedrock Knowledge Bases to connect with Amazon Redshift.

Load sample financial data

To load the finance datasets to Amazon Redshift, complete the following steps:

  1. Open the Amazon Redshift Query Editor V2 or another SQL editor of your choice and connect to the Redshift database.
  2. Run the following SQL to create the finance data tables and load sample data:
    -- Create table
    CREATE TABLE accounts (
        id integer ,
        account_id integer PRIMARY KEY,
        customer_id integer,
        account_type character varying(256),
        opening_date date,
        balance bigint,
        currency character varying(256)
    );
    
    CREATE TABLE customer (
        id integer,
        customer_id integer PRIMARY KEY ,
        name character varying(256) ,
        age integer,
        gender character varying(256) ,
        address character varying(256) ,
        phone character varying(256) ,
        email character varying(256)
    );
    
    CREATE TABLE investments (
        id integer ,
        investment_id integer PRIMARY KEY,
        customer_id integer ,
        investment_type character varying(256) ,
        investment_name character varying(256) ,
        purchase_date date ,
        purchase_price bigint ,
        quantity integer 
    );
    
    
    CREATE TABLE loans (
        id integer ,
        loan_id integer PRIMARY KEY,
        customer_id integer ,
        loan_type character varying(256) ,
        loan_amount bigint ,
        interest_rate integer ,
        start_date date ,
        end_date date 
    );
    
    CREATE TABLE orders (
        id integer ,
        order_id integer PRIMARY KEY,
        customer_id integer ,
        order_type character varying(256) ,
        order_date date ,
        investment_id integer ,
        quantity integer ,
        price integer 
    );
    
    CREATE TABLE transactions (
        id integer ,
        transaction_id integer PRIMARY KEY ,
        account_id integer REFERENCES accounts(account_id),
        transaction_type character varying(256) ,
        transaction_date date ,
        amount integer ,
        description character varying(256) 
    );

  3. Download the sample financial dataset to your local storage and unzip the zipped folder.
  4. Create an Amazon Simple Storage Service (Amazon S3) bucket with a unique name. For instructions, refer to Creating a general purpose bucket.
  5. Upload the downloaded files into your newly created S3 bucket.
  6. Using the following COPY command statements, load the datasets from Amazon S3 into the new tables you created in Amazon Redshift. Replace <<your_s3_bucket>> with the name of your S3 bucket and <<your_region>> with your AWS Region.
    -- Load sample data
    COPY accounts FROM 's3://<<your_s3_bucket>>/accounts.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    
    COPY customer FROM 's3://<<your_s3_bucket>>/customer.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY investments FROM 's3://<<your_s3_bucket>>/investments.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY loans FROM 's3://<<your_s3_bucket>>/loans.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY orders FROM 's3://<<your_s3_bucket>>/orders.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';
    COPY transactions FROM 's3://<<your_s3_bucket>>/transactions.csv' IAM_ROLE DEFAULT FORMAT AS CSV DELIMITER ',' QUOTE '"' IGNOREHEADER 1 REGION AS '<<your_region>>';

Enable LLM access

With Amazon Bedrock, you can access state-of-the-art AI models from providers like Anthropic, AI21 Labs, Stability AI, and Amazon’s own foundation models (FMs). These include Anthropic’s Claude 2, which excels at complex reasoning and content generation; Jurassic-2 from AI21 Labs, known for its multilingual capabilities; Stable Diffusion from Stability AI for image generation; and Amazon Titan models for various text and embedding tasks. For this demo, we use Amazon Bedrock to access the Amazon Nova FMs. Specifically, we use the Amazon Nova Pro model, which is a highly capable multimodal model designed for a wide range of tasks like video summarization, Q&A, mathematical reasoning, software development, and AI agents, including high speed and accuracy for text summarization tasks.

Make sure you have the required IAM permissions to enable access to available Amazon Bedrock Nova FMs. Then complete the following steps to enable model access in Amazon Bedrock:

  1. On the Amazon Bedrock console, in the navigation pane, choose Model access.
  2. Choose Enable specific models.
  3. Search for Amazon Nova models, select Nova Pro, and choose Next.
  4. Review the selection and choose Submit.

Create an Amazon Bedrock knowledge base referencing structured data in Amazon Redshift

Amazon Bedrock Knowledge Bases uses Amazon Redshift as the query engine to query your data. It reads metadata from your structured data store to generate SQL queries. There are different supported authentication methods to create the Amazon Bedrock knowledge base using Amazon Redshift. For more information, refer to the Set up query engine for your structured data store in Amazon Bedrock Knowledge Bases.

For this post, we create an Amazon Bedrock knowledge base for the Redshift database and sync the data using IAM authentication.

If you’re creating an Amazon Bedrock knowledge base through the AWS Management Console, you can skip the service role setup mentioned in the previous section. It automatically creates one with the necessary permissions for Amazon Bedrock Knowledge Bases to retrieve data from your new knowledge base and generate SQL queries for structured data stores.

When creating an Amazon Bedrock knowledge base using an API, you must attach IAM policies that grant permissions to create and manage knowledge bases with connected data stores. Refer to Prerequisites for creating an Amazon Bedrock Knowledge Base with a structured data store for instructions.

Complete the following steps to create an Amazon Bedrock knowledge base using structured data:

  1. On the Amazon Bedrock console, choose Knowledge Bases in the navigation pane.
  2. Choose Create and choose Knowledge Base with structure data store from the dropdown menu.
  3. Provide the following details for your knowledge base:
    1. Enter a name and optional description.
    2. Select Amazon Redshift as the query engine.
    3. Select Create and use a new service role for resource management.
    4. Make note of this newly created IAM role.
    5. Choose Next to proceed to the next part of the setup process.
    6. Configure the query engine:
      • Select Redshift Serverless (Amazon Redshift provisioned is also supported).
      • Choose your Redshift workgroup.
      • Use the IAM role created earlier.
      • Under Default storage metadata, select Amazon Redshift databases and for Database, choose dev.
      • You can customize settings by adding specific contexts to enhance the accuracy of the results.
      • Choose Next.
    7. Complete creating your knowledge base.
    8. Record the generated service role details.
    9. Next, grant appropriate access to the service role for Amazon Bedrock Knowledge Bases through the Amazon Redshift Query Editor V2. Update <your Service Role name> in the following statements with your service role, and update the value for <your schema>.
      CREATE USER "IAMR:<your Service Role name>" WITH PASSWORD DISABLE;
      SELECT * FROM PG_USER; -- To verify that the user is created.
      GRANT SELECT ON ALL TABLES IN SCHEMA <your schema> TO "IAMR:<your Service Role name>";
      --You can also Restricting access to certain tables for finer-grained control on the tables that can be accessed as shown below
      GRANT SELECT ON TABLE customer to "IAMR:<your Service Role name>";
      GRANT SELECT ON TABLE loan to "IAMR:<your Service Role name>";

Now you can update the knowledge base with the Redshift database.

  1. On the Amazon Bedrock console, choose Knowledge Bases in the navigation pane.
  2. Open the knowledge base you created.
  3. Select the dev Redshift database and choose Sync.

It may take a few minutes for the status to display as COMPLETE.

Ask queries and get responses in natural language

You can set up your application to query the knowledge base or attach the knowledge base to an agent by deploying your knowledge base for your AI application. For this demo, we use a native testing interface on the Amazon Bedrock Knowledge Bases console.

To ask questions in natural language on the knowledge base for Redshift data, complete the following steps:

  1. On the Amazon Bedrock console, open the details page for your knowledge base.
  2. Choose Test.
  3. Choose your category (Amazon), model (Nova Pro), and inference settings (On demand), and choose Apply.
  4. In the right pane of the console, test the knowledge base setup with Amazon Redshift by asking a few simple questions in natural language, such as “How many tables do I have in the database?” or “Give me list of all tables in the database.”

The following screenshot shows our results.

  1. To view the generated query from your Amazon Redshift based knowledge base, choose Show details next to the response.
  2. Next, ask questions related to the financial datasets loaded in Amazon Redshift using natural language prompts, such as, “Give me the name of the customer with the highest number of accounts” or “Give the details of all accounts for customer Deanna McCoy.”

The following screenshot shows the responses in natural language.

Using natural language queries in Amazon Bedrock, you were able to retrieve responses from the structured financial data stored in Amazon Redshift.

Considerations

In this section, we discuss some important considerations when using this solution.

Security and compliance

When integrating Amazon Bedrock with Amazon Redshift, implementing robust security measures is crucial. To protect your systems and data, implement essential safeguards including restricted database roles, read-only database instances, and proper input validation. These measures help prevent unauthorized access and potential system vulnerabilities. For more information, see Allow your Amazon Bedrock Knowledge Bases service role to access your data store.

Cost

You incur a cost for converting natural language to text based on SQL. To learn more, refer to Amazon Bedrock pricing.

Use custom contexts

To improve query accuracy, you can enhance SQL generation by providing custom context in two key ways. First, specify which tables to include or exclude, focusing the model on relevant data structures. Second, supply curated queries as examples, demonstrating the types of SQL queries you expect. These curated queries serve as valuable reference points, guiding the model to generate more accurate and relevant SQL outputs tailored to your specific needs. For more information, refer to Create a knowledge base by connecting to a structured data store.

For different workgroups, you can create separate knowledge bases for each group, with access only to their specific tables. Control data access by setting up role-based permissions in Amazon Redshift, verifying each role can only view and query authorized tables.

Clean up

To avoid incurring future charges, delete the Redshift Serverless instance or provisioned data warehouse created as part of the prerequisite steps.

Conclusion

Generative AI applications provide significant advantages in structured data management and analysis. The key benefits include:

  • Using natural language processing – This makes data warehouses more accessible and user-friendly
  • Enhancing customer experience – By providing more intuitive data interactions, it boosts overall customer satisfaction and engagement
  • Simplifying data warehouse navigation – Users can understand and explore data warehouse content through natural language interactions, improving ease of use
  • Improving operational efficiency – By automating routine tasks, it allows human resources to focus on more complex and strategic activities

In this post, we showed how the natural language querying capabilities of Amazon Bedrock Knowledge Bases when integrated with Amazon Redshift enables rapid solution development. This is particularly valuable for the finance industry, where financial planners, advisors, or bankers face challenges in accessing and analyzing large volumes of financial data in a secured and performant manner.

By enabling natural language interactions, you can bypass the traditional barriers of understanding database structures and SQL queries, and quickly access insights and provide real-time support. This streamlined approach accelerates decision-making and drives innovation by making complex data analysis accessible to non-technical users.

For additional details on Amazon Bedrock and Amazon Redshift integration, refer to Amazon Redshift ML integration with Amazon Bedrock.


About the authors

Nita Shah is an Analytics Specialist Solutions Architect at AWS based out of New York. She has been building data warehouse solutions for over 20 years and specializes in Amazon Redshift. She is focused on helping customers design and build enterprise-scale well-architected analytics and decision support platforms.

Sushmita Barthakur is a Senior Data Solutions Architect at Amazon Web Services (AWS), supporting Strategic customers architect their data workloads on AWS. With a background in data analytics, she has extensive experience helping customers architect and build enterprise data lakes, ETL workloads, data warehouses and data analytics solutions, both on-premises and the cloud. Sushmita is based in Florida and enjoys traveling, reading and playing tennis.

Jonathan Katz is a Principal Product Manager – Technical on the Amazon Redshift team and is based in New York. He is a Core Team member of the open source PostgreSQL project and an active open source contributor, including PostgreSQL and the pgvector project.

Insights from a teacher trainer: Schools are ready to engage in AI — what they need is support

Post Syndicated from Dan Shilling original https://www.raspberrypi.org/blog/insights-from-a-teacher-trainer-experience-ai/

Today’s blog post is written by Dan Shilling, Programmes Manager at Parent Zone, one of our global partners for Experience AI.

“Educators have been struggling to find resources and support to teach young people about AI.”

This is something I’ve heard a lot when delivering Experience AI teacher training through Parent Zone’s partnership with the Raspberry Pi Foundation. 

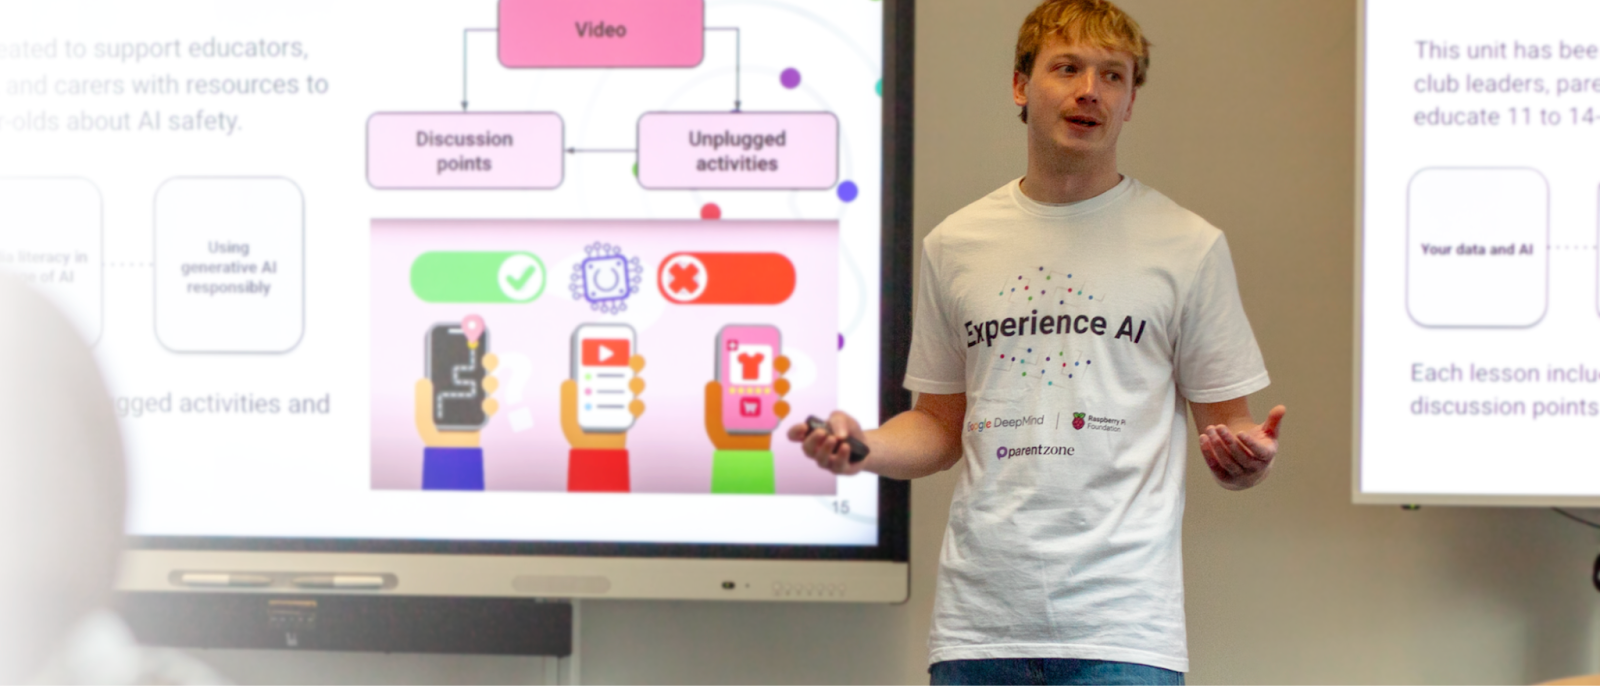
An educator is delivering a presentation during a workshop.

Our partnership with the Raspberry Pi Foundation

Experience AI is an artificial intelligence (AI) literacy programme, co-developed by the Raspberry Pi Foundation and Google DeepMind, that teaches students aged 11 to 14 about AI and machine learning. Thanks to funding from Google.org, Parent Zone has partnered with the Raspberry Pi Foundation to provide free training to UK educators, equipping them with the skills they need to effectively deliver the programme in their settings.

The Experience AI resources help educators, including those from non-technical backgrounds, to deliver impactful lessons on AI and machine learning. Lesson resources span technical elements (e.g. data-driven models, bias) and practical elements (e.g. careers, safety).

Our face-to-face and virtual training sessions show teachers how to use the programme resources, as well as helping them feel more confident in the subject matter.  

The sessions also give me an opportunity to hear from teachers about how AI is being used and taught in classrooms, and the opportunities and challenges it’s creating.

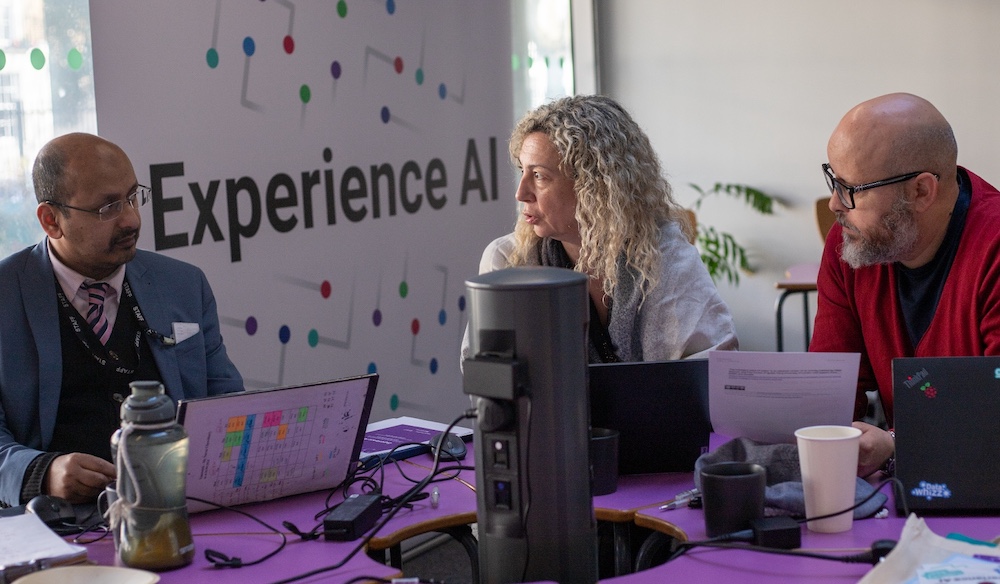
A group of educators at a workshop.

Curiosity and experimentation

AI has a major presence in many schools now. 

Teachers tell me they’re seeing students use AI to support their homework. One teacher spoke about a student using a chatbot to help break down a maths problem, describing it like “having a tutor at home.”

Teachers are also using AI themselves to assist in their work — for example, to plan lessons, generate activities, and get ideas on how to explain complex topics more clearly. 

Openness to experimentation is clearly there. 

Educators at a workshop.

Addressing concerns

For all the benefits of AI, teachers also have concerns about it. 

Some have told me their students have no idea how easily these tools can be used to mislead or manipulate, through disinformation and deepfakes, for example. 

This is why Experience AI resources are meeting educator needs. Not only do they explain how AI and machine learning actually work, but they also address many pressing concerns around AI, from responsible usage and media literacy, to how data bias can affect the final output.   

Positive changes

In all the workshops, what stands out to me most is how ready teachers are to engage. They want to understand more. They want to help their students make sense of AI, and use it positively. 

They’re grateful for practical, grounded training and support that doesn’t assume they’ve all got computer science degrees. After one of our sessions, a teacher said:

“The better we educate ourselves, the better we’re able to help young people. It’s important because it’s affecting their day-to-day lives. We can help them navigate AI platforms, but in a safe way.”

Educators at a workshop.

Join a network of AI-ready educators

If you’re a UK secondary school teacher, you can sign up for free training from Parent Zone, with dates available until November 2025. You can choose from:

For more information about Experience AI, visit our website.

The post Insights from a teacher trainer: Schools are ready to engage in AI — what they need is support appeared first on Raspberry Pi Foundation.

How to enhance your application resiliency using Amazon Q Developer

Post Syndicated from Dr. Rahul Sharad Gaikwad original https://aws.amazon.com/blogs/devops/how-to-enhance-your-application-resiliency-using-amazon-q-developer/

“Everything fails, all the time” – Werner Vogels, Amazon.com CTO

In today’s digital landscape, designing applications with resilience in mind is crucial. Resiliency is the ability of applications to handle failures gracefully, adapt to changing conditions, and recover swiftly from disruptions. By integrating resilience into your application architecture, you can minimize downtime, mitigate the impact of failures, and ensure continuous availability and performance for end-users.

Amazon Q Developer, a generative AI-powered assistant for software development lifecycle (SDLC), helps design resilient architectures and enhance application availability. It recommends best practices, analyzes code, and identifies potential failure points, serving as an expert companion to strengthen application architecture and boost system availability through the following key resiliency practices.

  • Resilient design pattern recommendations: Access tailored design patterns like distributed systems, microservices, and serverless architectures. Amazon Q offers recommendations across redundancy, robust failovers, and circuit breakers to boost resilience in your environment.
  • Disaster Recovery planning: Amazon Q offers expert guidance on comprehensive disaster recovery (DR), including efficient backups, systematic restorations, strategic data replication, and seamless failovers to ensure rapid recovery from disruptions with minimal impact.
  • Customized Resiliency testing frameworks: Create custom templates to simulate diverse failure scenarios, such as network degradation and infrastructure outages. This streamlines thorough resilience verification across your systems.
  • Failure mode evaluation: Use Amazon Q to conduct comprehensive Failure Mode and Effects Analysis (FMEA) identifying infrastructure vulnerabilities and assessing their impact. Amazon Q then ranks these issues by severity, enabling you to prioritize and address the most critical risks to protect your production environment.

In the following sections, we will demonstrate how Amazon Q improves the resiliency of a foundational application architecture.

Prerequisites

To begin using Amazon Q, the following are required:

Application Overview

We have a three-tier web application shown below that is running on AWS in a single Availability Zone (AZ). The architecture consists of Application Layer hosted on Amazon Elastic Kubernetes Service (Amazon EKS) cluster with two Amazon Elastic Compute Cloud (Amazon EC2) nodes in a single-AZ and the Data Layer uses Amazon Relational Database Service (Amazon RDS) instance deployed in single-AZ configuration. The architecture is functional but has several limitations. It poses a single point of failure and offers limited application availability with no fault tolerance. High response times may occur because there is no caching layer in front of the database. Additionally, the lack of auto-scaling can lead to resource contention.

A three-tier web application basic architecture running on AWS in a single Availability Zone.

Basic Application Overview

Enhance Application Resiliency

Let’s explore how Amazon Q helps incorporate resiliency best practices that enhance system availability in our basic application architecture.

Resilient architecture recommendations

The initial architecture faced challenges with reliability, performance and scalability, largely due to its single-point of failure and lacked redundancy. To address this, we described the existing application design and its challenges to Amazon Q using a natural language prompt to seek resiliency recommendations.

Prompt for improving the architecture design:

I have manually setup an application that runs within an EKS cluster on two EC2 nodes in single AZ. My application is not highly available and scalable. It talks to an RDS database which is single AZ. However, there is high response times from database. Provide me only the recommendations to re-design this application architecture at each layer that will addresses all these issues.

Amazon Q offering resiliency architecture recommendations

Amazon Q offering resiliency architecture recommendations

Amazon Q analyzed the provided context and recommended improvements such as introducing Multi-AZ deployments for high availability, adding auto-scaling groups for elasticity, and incorporating caching layers to enhance performance. These targeted recommendations helped redesign the architecture to be more resilient and scalable, directly addressing the initial shortcomings.

Disaster Recovery (DR) recommendations to improve the architecture

To further enhance resiliency, we prompted Amazon Q for disaster recovery (DR) recommendations. We asked for guidance aligned with the AWS Well-Architected Framework. This built upon the previously improved architecture design.

Prompt for recommendations on Disaster Recovery (DR) and architecture based on RTO/RPO

Based on the above improvements on AWS architecture design, share recommendations for Disaster Recovery (DR) based on AWS Well Architected Framework

Optionally, we can use advanced prompts like the below with additional context:

Please provide a recommendations to redesign my application that is running on an EKS cluster with two EC2 nodes and a single-AZ RDS database, addressing high database latency, low availability, and scalability issues. Suggest improvements across all architectural layers including presentation tier, application tier and data tier to enhance performance, resiliency, and scalability. Also, recommend DR strategies aligned with the AWS Well-Architected Framework focusing on resilience, data protection, and recovery.

Amazon Q tailoring recommendations based on business requirements using  AWS Well-Architected Framework

Amazon Q tailoring recommendations based on business requirements using AWS Well-Architected Framework

Amazon Q provided detailed DR strategies. These included multi-region configuration, backup and restore procedures, and best practices for meeting specific Recovery Time Objective (RTO) and Recovery Point Objective (RPO) requirements.

Prepare DR strategy based on RTO and RPO requirements:

Diving further, asking for a specific disaster recovery strategy that meets the application RTO requirements of 2 hours and RPO requirements of 30 minutes.

Prompt for DR strategy based on RTO/RPO values

Which DR strategy should I use if my RTO is less than 2 hours and RPO is less than 30 minutes?

Amazon Q recommending disaster recovery strategy

Amazon Q recommending disaster recovery strategy

Amazon Q recommended a Pilot light approach, detailing the setup and components needed to achieve the specified disaster recovery objectives.

Define resiliency testing workflow, identify key metrics and tools

As we incorporate resiliency best practices into the application architecture, its is important to employ a resiliency test workflow to ensure application’s resiliency requirements are met. To do this, we are asking for guidance to define an end-to-end resiliency testing process workflow. We also want to identify the key metrics and tools needed to test the resilience of each AWS service involved in the architecture.

Prompt for defining the resiliency testing workflow:

Define the end-to-end resiliency testing process workflow. Also, identify the key metrics and tools that should be used to test the resilience of each AWS service involved in the improved architecture design.

Amazon Q offering resiliency testing best practices and tools

Amazon Q offering resiliency testing best practices and tools

Amazon Q offers a step-by-step approach to define resiliency testing experiments and prepare the environment for testing.

Failure mode evaluation to prioritize resiliency tests

Failure Mode and Effects Analysis (FMEA) can further assist with designing the resiliency tests. It is a proactive method to identify potential failures in processes or systems, assess their impact, and prioritize critical issues. It evaluates failure modes across hardware, software, human factors, and external events, enabling teams to develop strategies for prevention, detection, and mitigation, ultimately enhancing system resilience.

Leveraging Amazon Q, we requested a comprehensive FMEA report that includes components, cause, effect and their respective Risk Priority Numbers (RPN). RPNs are calculated by multiplying three key factors: Severity (S), Occurrence (O), and Detection (D). It helps organizations understand and prioritize which risks to address first.

Prompt for designing the FMEA template and scoring:

Create the FMEA in tabular format with scoring for improved architecture design above keeping in mind the RTO/RPO values and provide the steps for execution as well.

Amazon Q assisting with systematic risk assessment and FMEA report

Amazon Q assisting with systematic risk assessment and FMEA report

Amazon Q intelligently incorporated previously defined RTO and RPO requirements to identify critical failure scenarios and calculated RPN for each potential incident.

Enhanced Architecture Implementing Resiliency Best Practices

After identifying the key pain points in our original architecture such as single points of failure, limited scalability, and lack of automated recovery, we leveraged Amazon Q to analyze our architecture to get targeted recommendations to elevate the resiliency. By describing our requirements and challenges to Amazon Q, we received actionable guidance on AWS best practices and service configurations, which we then implemented to transform our infrastructure for high resilience and availability.

Resilient Application Architecture

Resilient Application Architecture

The original Application Layer was running in a single Availability Zone without auto-scaling, leading to potential downtime and performance bottlenecks. Amazon Q recommended distributing Amazon EKS worker nodes across multiple Availability Zones and enabling the Cluster Autoscaler to dynamically adjust node capacity based on traffic patterns. Additionally, it suggested implementing horizontal pod autoscaling within Amazon EKS to automatically scale application resources according to CPU utilization and custom metrics. Following these recommendations, we deployed Amazon EKS worker nodes across three Availability Zones, configured Cluster Autoscaler and horizontal pod autoscaling, and integrated an Application Load Balancer, to intelligently distribute incoming traffic. These changes significantly improved scalability, fault tolerance, and performance.

The Data Layer initially relied on a single-instance Amazon RDS deployment, which posed a risk of downtime and limited read performance. Upon review, Amazon Q advised implementing a Multi-AZ Amazon RDS configuration to enable automated failover and improve availability. It also recommended deploying read replicas to offload read-heavy workloads and enhance performance. Furthermore, Amazon Q suggested adding a Multi-AZ Amazon ElastiCache for Redis to reduce database load and speed up data access. We incorporated these recommendations, resulting in a more resilient and performant data layer capable of handling failover scenarios and scaling read operations efficiently.

The Presentation Layer lacked an optimized content delivery mechanism and comprehensive security controls. Amazon Q recommended integrating Amazon CloudFront as a content delivery network to accelerate the delivery of static content and reduce load on application servers. It also suggested deploying AWS WAF to protect against common web exploits. To improve operational visibility, Amazon Q emphasized the importance of comprehensive monitoring using Amazon CloudWatch, combining logs, metrics, and traces for rapid issue detection and resolution. Implementing these recommendations enhanced both the performance and security posture of the presentation layer.

Conclusion

Amazon Q Developer transforms how teams build resilient applications by serving as your expert companion throughout the development journey. Its guidance helps create systems that excel in resilience, scalability, and availability—critical factors for today’s demanding digital landscape. Amazon Q goes beyond theoretical advice by providing practical, step-by-step implementation guidance. In the above, we’ve witnessed how Amazon Q’s expertise can transform basic architectures into robust, failure-resistant systems. Its recommendations such as Multi-AZ redundancy, elastic scaling, strategic caching, and proactive resilience testing create applications that maintain performance and availability even during significant disruptions.

Ready to strengthen your applications against unexpected challenges? Harness Amazon Q’s capabilities to create resilient infrastructure that consistently delivers for your customers, regardless of conditions. Unlock the full potential of your AWS infrastructure and deliver uninterrupted service to your customers, today. To learn more about Amazon Q refer to the documentation.

About the authors:

Dr. Rahul Sharad Gaikwad

Dr. Rahul is a Solutions Architect at AWS, driving cloud innovation through migration and modernization of customer workloads. A Generative AI and DevOps enthusiast, he architects cutting-edge solutions and is recognized as an APJC HashiCorp Ambassador. He earned his Ph.D. in AIOps and he is recipient of the Man of Excellence Award , Indian Achievers’ Award , Best PhD Thesis Award, Research Scholar of the Year Award and Young Researcher Award.

Janardhan Molumuri

Janardhan Molumuri is a Principal Technical Leader at AWS, comes with over two decades of Engineering leadership experience, advising customers on Cloud Adoption strategies and emerging technologies including generative AI. He has passion for thought leadership, speaking, writing, and enjoys exploring technology trends to solve problems at scale.

AI lifecycle risk management: ISO/IEC 42001:2023 for AI governance

Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/ai-lifecycle-risk-management-iso-iec-420012023-for-ai-governance/

As AI becomes central to business operations, so does the need for responsible AI governance. But how can you make sure that your AI systems are ethical, resilient, and aligned with compliance standards?

ISO/IEC 42001, the international management system standard for AI, offers a framework to help organizations implement AI governance across the lifecycle. In this post, we walk through how ISO/IEC 42001 enables effective AI governance, review the risk management requirements, and explore how you can use threat modeling as a practical technique to meet those expectations.

AI governance

AI governance refers to the organizational structures, policies, and controls that enable AI systems to be used responsibly, ethically, and safely. Governance spans the entire AI lifecycle and includes the following activities:

  • Setting the intended purpose and stakeholder alignment
  • Managing data, models, and deployment risks
  • Designing in explainability, bias mitigation, and traceability
  • Establishing accountability, monitoring, and decommissioning practices

These activities are the foundation of a formal framework that you can use to establish governance processes, identify and manage risk, and implement processes for continuous improvement

AI lifecycle

While ISO 42001 provides a framework for AI governance, ISO/IEC 22989:2022 describes what an AI system is and how it evolves. Governance should be implemented at every stage of the AI lifecycle to manage AI risks effectively. According to the ISO/IEC 22989:2022 standard, an organization’s AI life cycle might include these stages:

  1. Inception: Identifying needs, goals, and feasibility
  2. Design and development: Defining system architecture, data flows, and training models
  3. Verification and validation: Testing and confirming that the system meets requirements and performs as intended
  4. Deployment: Releasing the system into its operational environment
  5. Operation and monitoring: Running the system, logging activity, and monitoring performance and outcomes
  6. Re-evaluation: Assessing whether the system continues to meet objectives under changing conditions
  7. Retirement: Decommissioning the system and addressing long-term data and access risks

Understanding the AI lifecycle, shown in Figure 1 that follows, is critical for identifying and mitigating AI risks. While these seven stages are provided directly in ISO 22989:2022, your organization might define its AI lifecycle stages differently to suit its business context. We refer to these stages as we explore the components of an AI management system, from initial AI system scoping, through threat monitoring and risk assessment, to monitoring the established governance program.

Figure 1: Example of AI system lifecycle model stages and high-level processes based on ISO/IEC 22989:2022

Figure 1: Example of AI system lifecycle model stages and high-level processes based on ISO/IEC 22989:2022

Risk management in ISO/IEC 42001:2023

After an organization has identified and assessed AI risks (Clause 6.1 of ISO/IEC 42001:2023), operational controls to mitigate those risks must be implemented (Clause 8.2), and those controls and the AI system itself should be continuously monitored, documented, and improved (Clauses 9 and 10). AI impact assessments (AIIAs) are critical in high-risk use cases, complementing baseline risk assessments by focusing on societal, ethical, and legal impacts. AIIAs are like data protection impact assessments (DPIAs) for high-risk personal data processing under many privacy regulations. DPIAs are specifically designed to assess risks to individuals’ privacy and data protection rights under laws such as the GDPR. While AIIAs help organizations maintain responsible AI governance, DPIAs can be used in parallel to help verify that AI systems comply with data protection laws, together providing a holistic view of risks and safeguards across both ethical and legal dimensions.

You are free to select the AIIA tools or methodologies that best fit your use case. Two widely accepted frameworks are:

  • ISO 31000: A general-purpose enterprise risk management standard that helps identify, evaluate, and treat risks in a structured and repeatable way. It aligns well with organizations seeking to embed AI risk into their broader enterprise risk management (ERM) programs.
  • NIST AI Risk Management Framework (AI RMF): A NIST framework specifically designed for AI systems. It introduces tailored concepts such as explainability, robustness, fairness, and accountability, with actionable guidance organized into four core functions: Map, measure, manage, and govern.

ISO 42001 provides structured methods to conduct risk and impact assessments. Threat modeling tools such as:

  • STRIDE (spoofing, tampering, repudiation, information disclosure, denial of service, and elevation of privilege). STRIDE aims to make sure that a system meets security requirements for confidentiality, integrity and availability.
  • DREAD (damage potential, reproducibility, exploitability, affected users, and discoverability) is a framework that can assess severity of individual threats.
  • OWASP (Open Worldwide Application Security Project) for machine learning (ML) enables analysis of AI system vulnerabilities, adversarial risks, and privacy threats.

Trustworthy AI is the result of strategic governance, structured methodologies, and technical analysis.

Figure 2 that follows shows the tiered structure of AI risk governance, moving from high-level governance to detailed technical assessments. On the left side, there’s a downward flow representing the increasing depth of controls, while the right side shows an upward scale indicating escalating AI risks.

  • At the top layer, ISO/IEC 42001:2023 defines formal requirements for AI governance, including risk assessment mandates, control implementation, and lifecycle oversight.
  • The middle layer features widely adopted risk assessment methodologies and frameworks, such as ISO 31000 and the NIST AI Risk Management Framework (RMF), which provide structured methods to identify, evaluate, and mitigate AI risks.
  • At the base, are detailed threat modeling tools—including STRIDE, DREAD, PASTA, LINDDUN, and OWASP for ML—that support deep analysis of AI systems for vulnerabilities related to security, privacy, data protection, and adversarial threats.

Together, these layers form a comprehensive approach to AI risk governance, aligning strategic oversight with operational and technical defenses.

Figure 2: A layered approach to AI risk management aligned with ISO/IEC 42001. ISO/IEC 42001 defines AI governance for responsible AI

Figure 2: A layered approach to AI risk management aligned with ISO/IEC 42001. ISO/IEC 42001 defines AI governance for responsible AI

Threat modeling for AI risk identification

Threat modeling identifies AI lifecycle technical risks such as exploit surfaces, adversarial threats, and misuse scenarios that complement organizational risk analysis and impact assessments. This post takes a broader AI lifecycle view, showing you how threat modeling complements other risk strategies within the context of ISO/IEC 42001:2023. Additionally, AWS has published AI threat modeling guidance, such as:

The following table is an example STRIDE threat model for a generative AI resource using AWS services by AI lifecycle stage and risk type. This illustrates technical threat remediation through AWS cloud native governance features.

STRIDE category Example threat Lifecycle stage Risk type AWS feature for governance
Spoofing A fake identity uses the AI system to generate phishing emails or misinformation Inception Security AWS IAM Identity Center and Amazon Cognito for multi-factor authentication (MFA), Amazon GuardDuty for threat detection
Tampering A malicious prompt injection or API injection alters the model behavior or bypasses filters Design development Integrity Amazon Bedrock Guardrails, Amazon API Gateway and AWS WAF rules, AWS CloudTrail for input auditing
Repudiation Users deny prompt activity or content creation, and there’s no logging Verification and validation Accountability CloudTrail, Amazon Bedrock invocation logs, Amazon SageMaker ML Lineage Tracking for traceability
Information disclosure Sensitive internal data—such as code or personally identifiable information (PII)—accidentally learned and reproduced by the large language model (LLM) Operation and monitoring Privacy, Security SageMaker Clarify, AWS VPC PrivateLink, AWS Key Management Service (AWS KMS) encryption, Amazon Bedrock data handling commitments
Denial of service Bad actors overload the AI endpoint with prompt spam, degrading service Deployment Availability AWS Shield, API rate limiting using API Gateway, auto scaling with SageMaker endpoints
Elevation of privilege An internal user modifies system prompts or updates to override content filters Reevaluation Ethics and access control AWS Identity and Access Management (IAM) roles, Amazon Bedrock Guardrails, AWS Config, service control policies (SCPs)

While STRIDE is used here for illustrative clarity, it’s just one of several threat modeling approaches that can be applied depending on the system context. Other widely recognized methods include:

By integrating these threat modeling practices into ISO/IEC 42001’s risk-based approach, organizations are not just “checking compliance boxes” they’re operationalizing trustworthy, secure, and accountable AI governance throughout the full system lifecycle.

Threat modeling touchpoints across the AI lifecycle

ISO 42001:2023 uses the STRIDE threat modeling framework to align specific security threats to each stage. Each lifecycle stage is associated with particular threat types, relevant Annex references from the ISO standard, and examples of what to monitor.

  • Inception (Annex A.8.1): Focuses on spoofing and fake identity input risks.
  • Design and Development (Annex A.9.1): Linked to tampering threats.
  • Verification and Validation (Annex A.7.1): Concerns around repudiation, such as lack of model decision logs.
  • Deployment (Annex A.5.1): Addresses information disclosure vulnerabilities.
  • Operation and Monitoring (Annex A.10.3): Maps to denial-of-service attacks.
  • Re-evaluation (Annex A.8.6): Highlights risks of privilege escalation.

AI threat modeling isn’t a one-time task but must be applied continuously across each lifecycle stage, supported by ISO 42001’s annexes and STRIDE categories.

Figure 3: An illustration of how organizations can use ISO/IEC 42001:2023 as a structured framework for AI risk management, using threat modeling as a key technique across the AI lifecycle

Figure 3: An illustration of how organizations can use ISO/IEC 42001:2023 as a structured framework for AI risk management, using threat modeling as a key technique across the AI lifecycle

AWS tools for AI governance and risk management

AWS governance service capabilities support the controls required in the Statement of Applicability (SoA) under ISO/IEC 42001. These services and features help organizations operationalize responsible AI practices at scale and align with ISO/IEC 42001’s emphasis on structured, accountable AI lifecycle management.

  • Amazon SageMaker Model Cards: Provides standardized documentation for ML models including purpose, performance, and limitations. In the governance context, model cards help maintain transparency, accountability, and auditability of model behavior and use.
  • Amazon SageMaker Clarify: Detects bias in datasets and models and supports explainability of predictions. This directly supports governance controls related to fairness, non-discrimination, and explainability.
  • Amazon SageMaker Ground Truth: Provides high-quality, human-in-the-loop data labeling workflows. It supports data governance by making sure labeled datasets are accurate, consistent, and traceable.
  • Amazon Bedrock Guardrails: Can be used to define safety filters for generative AI, such as avoiding toxic content or harmful outputs. This facilitates alignment with ethical and content governance policies.
  • AWS CloudTrail and AWS Config: Enable audit logging and continuous monitoring of system changes. These are essential for accountability, traceability, and compliance reporting within AI governance frameworks.
  • AWS Identity and Access Management (IAM), AWS Key Management Service (AWS KMS), and AWS PrivateLink: IAM controls access, AWS KMS provides encryption and key management, and PrivateLink enables private connectivity. These features are critical for enforcing access governance, securing data, and maintaining privacy standards.
  • AWS Generative AI Lens: A part of the AWS Well-Architected Framework tool. It provides structured guidance for evaluating and improving the design of generative AI systems. It helps organizations implement responsible AI practices, manage risks

Conducting AI impact assessments for high risk use cases

While general risk assessments (Clause 6.1 of ISO/IEC 42001) are required for AI systems, ISO/IEC 42001 also calls for AIIAs in situations where the AI system poses high potential impact to individuals, groups, or society. AIIAs should result in a documented report of identified risks associated with the target AI activity, in addition to the severity of potential negative outcomes. These risks should be integrated into the AI management system (AIM) and monitored over time. Several stakeholders and specialists might need to provide input in the assessment process, such as legal, risk, compliance, data management, and security teams. Identified risks should be mitigated where possible, and a determination made about whether the residual risk is acceptable.

AIIAs help answer questions such as:

  • Is the AI use justifiable, ethical, and proportionate?
  • Could the system cause discrimination, exclusion, or loss of rights?
  • What safeguards should be built to protect affected people?

AIIA is required:

  • If the system makes or informs decisions that materially affect people
  • If the system is deployed in sensitive domains (such as healthcare, finance, or public services)
  • If risks to fundamental rights, fairness, or trust are flagged during initial risk assessments

AIAA should cover:

  • Purpose and scope of the AI system
  • Stakeholder and impact mapping
  • Legal, ethical, and social risk evaluation
  • Transparency and recourse mechanisms
  • Recommendations for mitigation

AIIA process workflow

Figure 4 that follows illustrates a generic AIIA workflow that includes initiating, scoping, assessing impact, planning mitigation, and documenting the outcome to evaluate how an AI system can affect individuals, groups, and society. Organizations can tailor this process to the AI system context, business objectives, and compliance requirements for their use case.

Figure 4: Sample prescriptive process with key phases on conducting an AIIA

Figure 4: Sample prescriptive process with key phases on conducting an AIIA

AIIA outcome

AIIA reports should capture the core purpose of the exercise: to evaluate how an AI system might affect individuals, communities, and society at large and to make sure that potential risks are addressed through appropriate mitigation strategies. While formats might vary across industries, an AIIA outcome typically includes key sections such as summary of system purpose, a mapping of affected stakeholders, a contextual analysis of legal and social factors, an evaluation of likely impacts (including fairness, bias, and autonomy risks) and a plan for a mitigation, oversight, and monitoring. Governance details such as sign off responsibility and reassessment triggers should also be included.

Whether you’re starting from scratch or adapting an existing template, these foundational elements will help make sure that your documentation supports transparency, accountability, and ethical AI deployment.

Templates:

Mapping AI lifecycle risks to ISO/IEC 42001 controls

After you have identified risks through techniques such as threat modeling and impact assessments, the next step is to make sure that they’re mitigated through the appropriate ISO/IEC 42001 controls. Using the lifecycle stages defined in ISO/IEC 22989:2022, you can map AI risks identified during the threat hunting process to the corresponding ISO/IEC 42001:2023 clauses and Annex A controls. This mapping helps you align your AI development and governance efforts with a standards-based risk framework.

AI lifecycle stage Identified risk Relevant ISO/IEC 42001 clauses Risk mitigation – Annex A controls
Inception Spoofing: Impersonation Clause 4, Clause 5 A.6.1 (Governance roles), A.5.1
Design and development Tampering: Unauthorized changes Clause 6.1, Clause 8.2 A.8.2, A.9.1
Verification and validation Repudiation: No traceability Clause 8.2 A.8.5, A.7.1
Deployment Elevation of privilege: Unauthorized model tweaks Clause 8.2, Clause 9.1 A.10.2, A.6.1
Operation and monitoring Denial of service: System overload Clause 9.1, Clause 10.1 A.8.3, A.10.3
Re-evaluation Drift and new threat vectors Clause 9.3, Clause 10.2 A.10.2, A.6.4
Retirement Information disclosure: Residual risks Clause 8.3, Clause 10.2 A.9.4, A.5.2

Maintaining AI governance

Like most technology risk and governance programs, AI management must be continuously monitored and maintained. ISO 42001 requires an organization to have leadership support and sufficient resources to operate effectively over time. This means that AI governance should be built into every process in the AI development and maintenance journey. AIIAs and threat modeling should be conducted at least annually on existing systems, and prior to the deployment of any new AI function. Policies should be reviewed at least annually and after major change to the AI system. Internal audits should review and monitor compliance with controls continuously, and organizations seeking ISO certification will require annual external audits. Progress toward governance goals and metrics on the status of known AI risks should be reported to the highest level of leadership in a live dashboard, and incidents of negative outcomes related to AI use should be tracked and analyzed to improve the AI system.

Conclusion

Managing AI risk effectively means aligning technical, organizational, and ethical considerations throughout the AI system lifecycle. ISO/IEC 42001 provides structure and accountability. Threat modeling techniques such as STRIDE, MITRE ATLAS, and OWASP for LLM surface deep technical risks. AWS services and features such as SageMaker Model Cards, SageMaker Clarify, and Amazon Bedrock Guardrails help embed governance into layers of AI development.

By combining technical tools, structured assessments, and standards-driven controls, you can build AI systems that are trustworthy, resilient, and aligned with societal expectations.

For additional guidance on achieving, maintaining, and automating compliance in the cloud, contact AWS Security Assurance Services (AWS SAS) or their account team. AWS SAS is a PCI QSAC and HITRUST Assessor Firm that can help by tying together applicable audit standards to AWS service specific features and functionality. They help you build on frameworks such as ISO 42001, PCI DSS, HITRUST CSF, NIST-CSF and Privacy Framework, SOC 2, HIPAA, ISO 27001 and 27701, and more. In addition, AWS Professional Services can also help you plan and map your compliance journey.

Disclaimer: The risk strategies and threat modeling guidance shared in this blog are intended to provide general direction and practical insight into implementing AI risk management under ISO/IEC 42001:2023. However, organizations are responsible for conducting their own context-specific risk assessments, as mandated by the standard. This blog should not be interpreted as an exhaustive approach to or guarantee of compliance with ISO/IEC 42001.

If you have feedback about this post, submit comments in the Comments section below.

Abdul Javid

Abdul Javid

Abdul is a Senior Security Assurance Consultant and a PECB ISO 42001 Lead Auditor and IAPP Certified AI Governance Professional. He draws on his extensive experience to guide AWS customers on compliance matters. He holds an M.S. in Computer Science from IIT Chicago and numerous certifications from IAPP, AWS, ISO, HITRUST, ISACA, PMI, PCI DSS, and ISC2.

Amber Welch

Amber Welch

Amber is a Senior Privacy Consultant with AWS Security Assurance Services and a PECB-certified ISO 42001 Lead Auditor. With extensive security and privacy management experience across industries, she advises AWS customers on compliance and risk management. She holds an M.A. in English – Technical Communication, CIPM and CIPP-E certifications, and is a thought leader in AI privacy, contributing to the AWS Privacy Reference Architecture.

Introducing the AWS User Guide to Governance, Risk and Compliance for Responsible AI Adoption within Financial Services Industries

Post Syndicated from Krish De original https://aws.amazon.com/blogs/security/introducing-the-aws-user-guide-to-governance-risk-and-compliance-for-responsible-ai-adoption-within-financial-services-industries/

Financial services institutions (FSIs) are increasingly adopting AI technologies to drive innovation and improve customer experiences. However, this adoption brings new governance, risk, and compliance (GRC) considerations that organizations need to address. To help FSI customers navigate these challenges, AWS is excited to announce the launch of the AWS User Guide to Governance, Risk and Compliance for Responsible AI Adoption within Financial Services Industries.

This comprehensive guide provides FSI customers practical considerations for responsible AI adoption across key dimensions including governance, risk management, compliance, data management, model management and AI agent management. It includes detailed AWS service capabilities that customers can use to address these considerations, such as Amazon Bedrock Guardrails, Amazon Bedrock Agents, Amazon SageMaker Autopilot, and Amazon SageMaker Model Monitor.

The guide is available through AWS Artifact and is complementary to other AWS resources such as the AWS Responsible Use of AI Guide, AWS Cloud Adoption Framework for AI, AWS Well-Architected Framework Generative AI Lens, and AWS Well-Architected Framework Machine Learning Lens.

As the regulatory environment and leading practices continue to evolve, we’ll provide further updates on the AWS Security Blog and AWS Compliance Center. You can also reach out to your AWS account team for help finding the resources you need.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Krish De
Krish De

Krish is a Principal FSI Governance, Risk & Compliance (GRC) specialist. He works with AWS customers, their regulators, and AWS teams to safely accelerate customers’ cloud adoption by providing prescriptive guidance on GRC. Krish has over 20 years of experience working in governance, risk, and technology across the financial services industry in Australia, New Zealand, and the United States.
Brenda Fong
Brenda Fong

Brenda is a senior FSI risk and compliance specialist. She works with AWS customers in banking, insurance, and capital markets within the ASEAN region to help them meet regulatory, governance, risk, and compliance expectations. Brenda has over 20 years of experience working in governance, risk, and technology across the financial services industry within Asia Pacific.
Kelvin Leung
Stephen Martin

Steve is the Head of Financial Services Compliance and Security for EMEA and APAC. Steve Joined AWS after working for over 20 years in financial service in senior leadership roles with responsibility across ASIA, the Middle East, and Europe. At AWS, he supports customers as they use the scale, security, and agility of AWS to transform the industry.
Kelvin Leung
Kelvin Leung

Kelvin is the AWS FSI Security and Compliance Lead based in Hong Kong. He has 20 years of experience in the IT and cloud regulatory space, with a focus on IT outsourcing, information security, and compliance. Prior to joining AWS, Kelvin worked for a financial regulator where he was responsible for technology risk policy-making and IT regulatory examinations.

Amazon OpenSearch Service launches flow builder to empower rapid AI search innovation

Post Syndicated from Dylan Tong original https://aws.amazon.com/blogs/big-data/amazon-opensearch-service-launches-flow-builder-to-empower-rapid-ai-search-innovation/

You can now access the AI search flow builder on OpenSearch 2.19+ domains with Amazon OpenSearch Service and begin innovating AI search applications faster. Through a visual designer, you can configure custom AI search flows—a series of AI-driven data enrichments performed during ingestion and search. You can build and run these AI search flows on OpenSearch to power AI search applications on OpenSearch without you having to build and maintain custom middleware.

Applications are increasingly using AI and search to reinvent and improve user interactions, content discovery, and automation to uplift business outcomes. These innovations run AI search flows to uncover relevant information through semantic, cross-language, and content understanding; adapt information ranking to individual behaviors; and enable guided conversations to pinpoint answers. Nonetheless, search engines are limited in native AI-enhanced search support, so builders develop middleware to complement search engines to fill in functional gaps. This middleware consists of custom code that runs data flows to stitch data transformations, search queries, and AI enrichments in varying combinations tailored to use cases, datasets, and requirements.

With the new AI search flow builder for OpenSearch, you have a collaborative environment to design and run AI search flows on OpenSearch. You can find the visual designer within OpenSearch Dashboards under AI Search Flows, and get started quickly by launching preconfigured flow templates for popular use cases like semantic, multimodal or hybrid search, and retrieval augmented generation (RAG). Through configurations, you can create customize flows to enrich search and index processes through AI providers like Amazon Bedrock, Amazon SageMaker, Amazon Comprehend, OpenAI, DeepSeek, and Cohere. Flows can be programmatically exported, deployed, and scaled on any OpenSearch 2.19+ cluster through OpenSearch’s existing ingest, index, workflow and search APIs.

In the remainder of the post, we’ll walk through a couple of scenarios to demonstrate the flow builder. First, we’ll enable semantic search on your old keyword-based OpenSearch application without client-side code changes. Next, we’ll create a multi-modal RAG flow, to showcase how you can redefine image discovery within your applications.

AI search flow builder key concepts

Before we get started, let’s cover some key concepts. You can use the flow builder through APIs or a visual designer. The visual designer is recommended for helping you manage workflow projects. Each project contains at least one ingest or search flow. Flows are a pipeline of processor resources. Each processor applies a type of data transform such as encoding text into vector embeddings, or summarizing search results with a chatbot AI service.

Ingest flows are created to enrich data as it’s added to an index. They consist of:

  1. A data sample of the documents you want to index.
  2. A pipeline of processors that apply transforms on ingested documents.
  3. An index constructed from the processed documents.

Search flows are created to dynamically enrich search request and results. They consist of:

  1. A query interface based on the search API, defining how the flow is queried and ran.
  2. A pipeline of processors that transform the request context or search results.

Generally, the path from prototype to production starts with deploying your AI connectors, designing flows from a data sample, then exporting your flows from a development cluster to a preproduction environment for testing at-scale.

Scenario 1: Enable semantic search on an OpenSearch application without client-side code changes

In this scenario, we have a product catalog that was built on OpenSearch a decade ago. We aim to improve its search quality, and in turn, uplift purchases. The catalog has search quality issues, for instance, a search for “NBA,” doesn’t surface basketball merchandise. The application is also untouched for a decade, so we aim to avoid changes to client-side code to reduce risk and implementation effort.

A solution requires the following:

  • An ingest flow to generate text embeddings (vectors) from text in an existing index.
  • A search flow that encodes search terms into text embeddings, and dynamically rewrites keyword-type match queries into a k-NN (vector) query to run a semantic search on the encoded terms. The rewrite allows your application to transparently run semantic-type queries through keyword-type queries.

We will also evaluate a second-stage reranking flow, which uses a cross-encoder to rerank results as it can potentially boost search quality.

We’ll accomplish our task through the flow builder. We begin by navigating to AI Search Flows in the OpenSearch Dashboard, and selecting Semantic Search from the template catalog.

image of the flow template catalog.

This template requires us to select a text embedding model. We’ll use Amazon Bedrock Titan Text, which was deployed as a prerequisite. Once the template is configured, we enter the designer’s main interface. From the preview, we can see that the template consists of a preset ingestion and search flow.

image of the visual flow designer.

The ingest flow requires us to provide a data sample. Our product catalog is currently served by an index containing the Amazon product dataset, so we import a data sample from this index.

importing a data sample from an existing index.

The ingest flow includes a ML Inference Ingest Processor, which generates machine learning (ML) model outputs such as embeddings (vectors) as your data is ingested into OpenSearch. As previously configured, the processor is set to use Amazon Titan Text to generate text embeddings. We map the data field that holds our product descriptions to the model’s inputText field to enable embedding generation.

Configuring the ML Inference Ingest Processor to generate text embeddings.

We can now run our ingest flow, which builds a new index containing our data sample embeddings. We can inspect the index’s contents to confirm that the embeddings were successfully generated.

Inspect your new index and embeddings from the flow designer.

Once we have an index, we can configure our search flow. We’ll start with updating the query interface, which is preset to a basic match query. The placeholder my_text has to be replaced with the product descriptions. With this update, our search flow can now respond to queries from our legacy application.

Update the search flow’s query interface

The search flow includes an ML Inference Search Processor. As previously configured, it’s set to use Amazon Titan Text. Since it’s added under Transform query, it’s applied to query requests. In this case, it will transform search terms into text embeddings (a query vector). The designer lists the variables from the query interface, allowing us to map the search terms (query.match.text.query), to the model’s inputText field. Text embeddings will now be generated from the search terms whenever our index is queried.

Configure a ML Inference Search Processor to generate query vectors.

Next, we update the query rewrite configurations, which is preset to rewrite the match query into a k-NN query. We replace the placeholder my_embedding with the query field assigned to your embeddings. Note that we could rewrite this to another query type, including a hybrid query, which may improve search quality.

Configure a query rewrite.

Let’s compare our semantic and keyword solutions from the search comparison tool. Both solutions are able to find basketball merchandise when we search for “basketball.”

Keyword versus semantic search results on the term “basketball”.

But what happens if we search for “NBA?” Only our semantic search flow returns results because it detects the semantic similarities between “NBA” and “basketball.”

Keyword versus semantic search results on the term “NBA”.

We’ve managed improvements, but we might be able to do better. Let’s see if reranking our search results with a cross-encoder helps. We’ll add a ML Inference Search Processor under Transform response, so that the processor applies to search results, and select Cohere Rerank. From the designer, we see that Cohere Rerank requires a list of documents and the query context as input. Data transformations are needed to package the search results into a format that can be processed by Cohere Rerank. So, we apply JSONPath expressions to extract the query context, flatten data structures, and pack the product descriptions from our documents into a list.

configure a ML Inference Search Processor with a reranker and apply JSONPath expressions.

Let’s return to the search comparison tool to compare our flow variations. We don’t observe any meaningful difference in our previous search for “basketball” and “NBA.” However, improvements are observed when we search, “hot weather.” On the right, we see that the second and fifth search hit moved 32 and 62 spots up, and returned “sandals” that are well suited for “hot weather.”

Reranked search results for “hot weather” demonstrate search quality gains.

We’re ready to proceed to production, so we export our flows from our development cluster into our preproduction environment, use the workflow APIs to integrate our flows into automations, and scale our test processes through the bulk, ingest and search APIs.

Scenario 2: Use generative AI to redefine and elevate image search

In this scenario, we have photos of millions of fashion designs. We’re looking for a low-maintenance image search solution. We will use generative multimodal AI to modernize image search, eliminating the need for labor to maintain image tags and other metadata.

Our solution requires the following:

  • An ingest flow which uses a multimodal model like Amazon Titan Multimodal Embeddings G1 to generate image embeddings.
  • A search flow which generates text embeddings with a multimodal model, runs a k-NN query for text to image matching, and sends matching images to a generative model like Anthropic’s Claude Sonnet 3.7 that can operate on text and images.

We’ll start from the RAG with Vector Retrieval template. With this template, we can quickly configure a basic RAG flow. The template requires an embedding and large language model (LLM) that can process text and image content. We use Amazon Bedrock Titan Multimodal G1 and Anthropic’s Claude Sonnet 3.7, respectively.

From the designer’s preview panel, we can see similarities between this template and the semantic search template. Again, we seed the ingest flow with a data sample. Like the previous example, we use the Amazon product dataset except we replace the production descriptions with base64 encoded images because our models require base64 images, and this solution doesn’t require text. We map the base64 image data to the corresponding Amazon Titan G1 inputs to generate embeddings. We then run our ingest flow and confirm that our index contains base64 images and corresponding embeddings.

Ingest flow creates a new index containing base64 images and corresponding embeddings.

The initial steps for configuring this search flow are similar to the previous scenario: we update the query interface, map the query text fields to the model inputs for the ML Inference Search Processor, and revise the query rewrite settings. The main difference with this flow is the additional response processor set to use Anthropic’s Claude Sonnet 3.7 to process images.

We need to configure an LLM prompt that includes the query context and instructions for the LLM to play the role of a fashion advisor, and provide commentary about the image payload.

configure a LLM prompt to generate commentary for product images.

Next, we map the prompt and the base64 image data field to the model’s inputs accordingly.

Configure the ML Inference Search Processor to process search results with Anthropic Claude Sonnet 3.7.

Let’s test our multimodal RAG flow by searching for “sunset colored dresses.” We observe the following results.

This beautiful dress perfectly captures the essence of a sunset with its gorgeous ombre color gradient. Starting with a soft peachy pink at the top, it transitions into a vibrant orange in the middle, and finishes with a bright yellow at the hem – just like the colors of the sky as the sun dips below the horizon. The dress features a simple, casual silhouette with short cap sleeves and appears to have a comfortable, relaxed fit that would flatter many body types. The tie-dye effect gives it a bohemian, carefree vibe that’s perfect for summer outings, beach vacations, or casual evening events. I recommend this sunset-colored dress because it’s eye-catching, versatile, and embodies that magical sunset glow that can brighten any occasion. The colors would complement warm skin tones particularly well, and you could easily dress it up with gold accessories or keep it casual with simple sandals.
This vibrant tie-dye dress perfectly captures the essence of a sunset with its beautiful gradient of colors. The dress features bands of golden yellow, fiery orange, and rich pink that blend together seamlessly, reminiscent of the sky at dusk. The strapless design showcases the shoulders elegantly, while the gathered waist creates a flattering silhouette that flows into a comfortable, knee-length skirt. This dress would be an excellent choice for summer events, beach vacations, or casual outings. The sunset color palette is not only on-trend but also versatile enough to pair with neutral accessories. I recommend this piece for its eye-catching colors, comfortable fit, and the way it embodies the warm, relaxed feeling of watching a beautiful sunset.

Without any image metadata, OpenSearch finds images of sunset-colored dresses, and responds with accurate and colorful commentary.

Conclusion

The AI search flow builder is available in all AWS Regions that support OpenSearch 2.19+ on OpenSearch Service. To learn more, refer to Building AI search workflows in OpenSearch Dashboards, and the available tutorials on GitHub, which demonstrate how to integrate various AI models from Amazon Bedrock, SageMaker, and other AWS and third-party AI services.


About the authors

Dylan Tong is a Senior Product Manager at Amazon Web Services. He leads the product initiatives for AI and machine learning (ML) on OpenSearch including OpenSearch’s vector database capabilities. Dylan has decades of experience working directly with customers and creating products and solutions in the database, analytics and AI/ML domain. Dylan holds a BSc and MEng degree in Computer Science from Cornell University.

Tyler Ohlsen is a software engineer at Amazon Web Services focusing mostly on the OpenSearch Anomaly Detection and Flow Framework plugins.

Mingshi Liu is a Machine Learning Engineer at OpenSearch, primarily contributing to OpenSearch, ML Commons and Search Processors repo. Her work focuses on developing and integrating machine learning features for search technologies and other open-source projects.

Ka Ming Leung (Ming) is a Senior UX designer at OpenSearch, focusing on ML-powered search developer experiences as well as designing observability and cluster management features.

Use an Amazon Bedrock powered chatbot with Amazon Security Lake to help investigate incidents

Post Syndicated from Madhunika Reddy Mikkili original https://aws.amazon.com/blogs/security/use-an-amazon-bedrock-powered-chatbot-with-amazon-security-lake-to-help-investigate-incidents/

In part 2 of this series, we showed you how to use Amazon SageMaker Studio notebooks with natural language input to assist with threat hunting. This is done by using SageMaker Studio to automatically generate and run SQL queries on Amazon Athena with Amazon Bedrock and Amazon Security Lake. The Security Lake service team and the Open Cybersecurity Schema Framework (OCSF) community continue to add additional log sources and OCSF mappings to enable Security Lake to provide a consolidated source for customers to conduct security investigation.

Because security logging data sources continually grow, organizations need to provide a mechanism for their security teams to understand and query those data sources. You might have existing investigation and response playbooks that your security teams need to be well-versed in and know when to use. It can take security teams an extended period of time to onboard and understand the available security data sources and playbooks and how to efficiently use them to reduce the mean time to respond.

In this post, we show you how to extend the functionality from the previous post. You will learn how to deploy a security chatbot with a graphical user interface (GUI) and a serverless backend powered by an Amazon Bedrock agent that incorporates existing playbooks to investigate or respond to a security event. The chatbot demonstrates purpose-built Amazon Bedrock agents that help address security concerns depending on the user’s natural language input. The solution has a single GUI that provides a direct interface with the Amazon Bedrock agent to create and invoke SQL queries or provide recommendations for internal incident response playbooks to investigate or respond to possible security events.

Security chatbot sample solution overview

Figure 1: Security chatbot sample solution architecture diagram

Figure 1: Security chatbot sample solution architecture diagram

Application flow as shown in Figure 1:

  1. User submits a query through the React UI.

    Note: The React UI used in this solution doesn’t have authentication built in. It’s recommended that you add authentication capabilities that follow your organization’s security requirements. You can add authentication capabilities by using Amazon Cognito and AWS Amplify UI.

  2. The user’s query is sent to an Amazon API Gateway REST API, which invokes the Invoke Agent AWS Lambda function.
  3. The Lambda function invokes the Amazon Bedrock agent with the user’s query.
  4. The Amazon Bedrock agent (using Anthropic’s Claude 3 Sonnet) processes the query and decides between retrieving information from the playbooks or by querying Security Lake using Amazon Athena.

For playbook knowledge base queries:

  1. The Amazon Bedrock agent queries the playbooks knowledge base and retrieves relevant results.

For Security Lake data queries:

  1. The Amazon Bedrock agent queries the schema knowledge base and retrieves the Security Lake table schemas to create an SQL query.
  2. The Amazon Bedrock agent invokes the SQL query action from the Amazon Bedrock action group, passing the SQL query as a parameter.
  3. The action group invokes the Execute SQL on Athena Lambda function, which executes the query on Athena and returns the results to the Amazon Bedrock agent.

After retrieving results from the knowledge base or action group:

  1. The Amazon Bedrock agent uses the retrieved information to formulate the final response and sends it back to the Invoke Agent Lambda function.
  2. The Lambda function sends the response back to the client using an API Gateway WebSocket API.
  3. API Gateway delivers the response to the React UI using a WebSocket connection to the client.
  4. The agent’s response is displayed to the user in the chat interface.

Prerequisites

Before deploying the sample solution, complete the following prerequisites:

  1. Enable Security Lake in your organization in AWS Organizations and specify a delegated administrator account to manage the Security Lake configuration for all member accounts in your organization. Configure Security Lake with the appropriate log sources: Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, AWS Security Hub, AWS CloudTrail, and Amazon Route53.
  2. Create subscriber query access from the source Security Lake AWS account to the subscriber AWS account.
  3. Accept a resource share request in the subscriber AWS account in AWS Resource Access Manager (AWS RAM).
  4. Create a database link in AWS Lake Formation in the subscriber AWS account and grant access for the Athena tables in the Security Lake AWS account.
  5. Grant Anthropic’s Claude v3 model access for Amazon Bedrock in the AWS subscriber account where you will deploy the solution. If you try to use a model before you enable it in your AWS account, you will get an error message.

With the prerequisites in place, the sample solution architecture provisions the following resources:

  1. Amazon CloudFront with an Amazon Simple Storage Service (Amazon S3) origin.
  2. An Amazon S3 static website for the chatbot UI.
  3. An API Gateway to call a Lambda function.
  4. A Lambda function to invoke the Amazon Bedrock agent.
  5. An Amazon Bedrock agent with a knowledge base.
    1. An Amazon Bedrock agent action group to generate and invoke SQL queries on Athena.
      1. An Amazon Bedrock knowledge base to reference example Athena table schemas in Security Lake. Although the Amazon Bedrock agent can get rows directly from the Athena table, providing example table schemas improves SQL query generation accuracy for table columns in Security Lake.
      2. An Amazon Bedrock knowledge base to reference existing incident response playbooks. By incorporating this knowledge base, the Amazon Bedrock agent can suggest actions for investigation or response based on existing playbooks that have already been approved by your organization.

Cost

Before deploying the sample solution and walking through this post, it’s important to understand the cost of the AWS services being used. The cost will largely depend on the amount of data you interact with in Amazon Bedrock and by querying Security Lake with Athena.

  1. Security Lake costs are determined by the volume of log and event data ingested from AWS services. Security Lake orchestrates other AWS services on your behalf, which incur separate charges. You can find more information on pricing for the respective services: Amazon S3, AWS Glue, Amazon EventBridge, AWS Lambda, Amazon Simple Query Service (Amazon SQS), and Amazon Simple Notification Service (Amazon SNS).
  2. Amazon Bedrock on-demand pricing is based on the selected large language model (LLM) and the number of input and output tokens. A token is comprised of a few characters and refers to the basic unit of text that a model learns to understand the user input and prompts. For more details, see Amazon Bedrock pricing.
  3. The SQL queries generated by Amazon Bedrock are invoked using Athena. Athena cost is based on the amount of data scanned within Security Lake for that query. For more details, see Athena pricing.

Deploy the sample chatbot

You can deploy the sample solution by using AWS Cloud Development Kit (AWS CDK). For instructions and more information on using the AWS CDK, see Get Started with AWS CDK.

  1. Clone the sample-generative-ai-chatbot-for-amazon-security-lake repository.
  2. Navigate to the project’s root folder.
  3. Install the project dependencies.
  4. Build and deploy the app using the following commands:
    npm install -g aws-cdk
    npm install 
    cdk synth
    

  5. Run the following commands in your terminal while signed in to your subscriber AWS account. Replace <INSERT_AWS_ACCOUNT> with your account number and replace <INSERT_REGION> with the AWS Region that you want the solution deployed to.
    cdk bootstrap aws://<INSERT_AWS_ACCOUNT>/<INSERT_REGION>
    cdk deploy –all
    

As part of the CDK deployment, there is an Output value for the React Application URL (FrontendAppStack.ReactAppUrl). You will use this value to interact with the GenAI application. Wait up to 5 mins for the URL to be live.

Post-deployment configuration steps

Now that you’ve deployed the solution, you need to add permissions to allow the Lambda function’s AWS Identity and Access Management (IAM) role and Amazon Bedrock to interact with your Security Lake data.

Grant permission to the Security Lake database

  1. Copy the Lambda’s role ARN from the “BedrockAppStack” CloudFormation stack. The resource in the stack is named “athenaAgentSecurityLakeActionGroupLambdaServiceRole********”.
  2. Go to the Lake Formation console.
  3. Select the amazon_security_lake_glue_db_<YOUR-REGION> database. For example, if your Security Lake is in us-east-1, the value would be amazon_security_lake_glue_db_us_east_1
  4. For Actions, select Grant.
  5. In Grant Data Permissions, select SAML Users and Groups.
  6. Paste the Lambda function IAM role ARN from Step 1.
  7. In Database Permissions, select Describe, and then choose Grant.

Grant permission to Security Lake tables

You must repeat the following steps for each source configured within Security Lake. For example, if you have four sources configured within Security Lake, you must grant permissions for the Lambda function IAM role to each table. If you have multiple sources that are in separate Regions and you don’t have a rollup Region configured in Security Lake, you must repeat the steps for each source in each Region.

The following example grants permissions to the Security Hub table within Security Lake. For more information about granting table permissions, see the AWS Lake Formation user guide.

  1. Copy the Lambda’s role ARN from the “BedrockAppStack” CloudFormation stack. The resource in the stack is named as “athenaAgentSecurityLakeActionGroupLambdaServiceRole********”.
  2. Go to the Lake Formation console.
  3. Select the amazon_security_lake_glue_db_<YOUR-REGION> database.
    For example, if your Security Lake database is in us-east-1, the value would be amazon_security_lake_glue_db_us_east-1
  4. Choose View Tables.
  5. Select the amazon_security_lake_table_<YOUR-REGION>_sh_findings_1_0 table.
    For example, if your Security Lake table is in us-east-1, the value would be amazon_security_lake_table_us_east_1_sh_findings_1_0

    Note: Each table must be granted access individually. Selecting All Tables won’t grant the access needed to query Security Lake.

  6. For Actions, select Grant.
  7. In Grant Data Permissions, select SAML Users and Groups.
  8. Paste the Lambda function IAM role ARN from Step 1.
  9. In Table Permissions, select Describe, and then Grant.

Sync data sources

After you deploy the infrastructure, you need to sync the data sources in the Amazon Bedrock knowledge bases so that the data in Amazon S3 can be vectorized and made available in Amazon OpenSearch Serverless, which is the service used as a vector source by the knowledge bases in this solution.

  • In the Amazon Bedrock console, select Knowledge base and find the two Amazon Bedrock knowledge bases deployed in this solution: gen-ai-sec-lake-table-schema and gen-ai-sec-lake-runbooks. Navigate to each knowledge base and its data source. Then choose Sync for each data source.

Get the CloudFront distribution URL

As part of the sample solution, the chatbot uses an externally available CloudFront distribution URL. It’s recommended that you add appropriate security controls that align to your organization’s security requirements to the sample solution. For example, you might want to add authentication to CloudFront using Amazon Cognito and Lambda@Edge to help prevent unauthorized users from accessing this chatbot. You can also configure secure access and restrict access to the content.

  1. Navigate to CloudFormation in the console.
  2. In the Stacks section, select the FrontendAppStack.
  3. Select the Outputs tab.
  4. Copy the value ReactAppUrl.

Investigate with your security chatbot

Now that you’ve deployed the sample solution and configured the appropriate permissions, you’re ready to use natural language input to generate and invoke SQL queries and to recommend internal incident response playbooks.

Generate and invoke SQL queries

Although most security professionals already know how to create and invoke SQL queries, time is extremely important during a possible security event. Adding natural-language-to-SQL capability to the security agent can help reduce your mean time to respond, which can reduce the overall impact of a security event. Furthermore, you can use these same techniques for threat hunting in your AWS environment.

Question 1: Which AWS accounts have the most security findings for EC2 instances in the last 7 days?

Answer 1: The query results show the top two AWS accounts with the most security findings related to EC2 instances in the last 7 days. The account with ID XXXXXX10 had the highest number of findings at 252, followed by account XXXXXX28 with 197 findings.

The query covered the key requirements, so I provided the final answer summarizing the top accounts and their finding counts.

The question and response are shown in Figure 2.

Figure 2: Response for most EC2 security findings

Figure 2: Response for most EC2 security findings

The more context you provide to the chatbot, the better the query that will be generated. Providing a time window also gives a smaller data set to review and give quicker results.

Question 2: In those AWS accounts, what were the top EC2 security finding types?

Answer 2: Based on the query results, the top EC2 security finding types in the AWS accounts with the most EC2 instance findings in the last 7 days were:

For account XXXXXX10:

  1. “Compliance Finding: Update” with 252 findings

For account XXXXXX28:

  1. “Compliance Finding Update” with 166 findings
  2. “Compliance Finding Create” with 24 findings
  3. “Vulnerability Finding: Update” with 2 findings
  4. “Vulnerability Finding: Create” with 2 findings.

The question and response are shown in Figure 3.

Figure 3: Response for top EC2 security finding types

Figure 3: Response for top EC2 security finding types

The results show that the issues are primarily around Security Hub controls mapped to the type_name OCSF column. If you want to look at a different column, you can provide additional instructions or update the question.

Question 3: Which EC2 instances had vulnerability security findings?

Answer 3: Based on the query results, the following EC2 instances had vulnerability security findings in the AWS account with the most EC2 instance findings in the last 7 days:

In account XXXXXX28:

  1. arn:aws:ec2:us-east-1: XXXXXX28:instance/<instance-id>
  2. arn:aws:ec2:us-east-1: XXXXXX28:instance/<instance-id>

There were no vulnerability findings for EC2 instances in account XXXXXX10 during this time period.

The question and response are shown in Figure 4.

Figure 4: Response for EC2 instances with vulnerability security findings

Figure 4: Response for EC2 instances with vulnerability security findings

In this question, the search is narrowed down to two Amazon Elastic Compute Cloud (Amazon EC2) instances within a specific AWS account to take a deeper look into.

Recommend incident response playbooks

As part of this sample solution, we used the AWS Incident Response Playbook Samples GitHub repository and uploaded them to an S3 bucket. Alternatively, you can create or reference your own playbooks to investigate and respond to various security events to refer to. After each question, the chatbot provides an answer along with an Amazon S3 URL to the playbook. The security analyst must have the appropriate permissions to download the playbook from Amazon S3.

Question 1: Do I have any playbooks that would help investigate a compromised EC2 instance for crypto mining or malware?

Answer 1: Yes, the search results include a relevant playbook for investigating a potentially compromised EC2 instance that could be used for crypto mining, malware, or ransomware. The key steps outlined in the playbook are:

  1. Acquire, preserve, and document evidence – Identify indicators of compromise, determine attack vector, document impacted applications/users
  2. Contain the incident – Isolate the compromised instance if possible without service disruption, remove from auto-scaling group if applicable
  3. Eradicate the incident – Follow the steps to remove the malware/crypto miner, restore from known good backups/AMIs
  4. Recovery – Spin up new instances from trusted AMIs, restore the data, and monitor for persistence of the threat
  5. Lessons learned – Analyze the incident, identify root causes, and implement preventative measures

The playbook provides detailed guidance on each of these phases in the context of an EC2 ransomware incident, but the overall process can be adapted for investigating crypto mining, malware, or other threats on EC2 as well.

The question and response are shown in Figure 5.

Figure 5: Response for EC2 IR playbooks

Figure 5: Response for EC2 IR playbooks

The previous threat-hunting exercise identified two EC2 instances that had vulnerabilities present. After further investigation, if a security analyst believes the EC2 instance is compromised, they can ask for an IR playbook to respond to the security event. Once they determine which playbook makes the most sense, they can either click on the S3 URL or look at other playbooks to use.

Question 2: Do I have any playbooks that would help respond to ransomware in my S3 bucket?

Answer 2: Yes, the search results include a playbook that can help respond to a ransomware incident involving an S3 bucket. The “Incident Response Playbook Template for Unintended Access to an Amazon S3 Bucket” outlines steps for:

  1. Gathering evidence of the unintended access
  2. Containing the incident by restricting access to the affected bucket(s)
  3. Eradicating the issue by removing any malicious data/objects and restoring from backup
  4. Recovering by re-enablement access to the bucket for legitimate users
  5. Conducting post-incident activities like reviewing logs, determining root cause, and implementing preventative measures

While focused on generic unintended access rather than ransomware specifically, many of these steps could be adapted and applied to a ransomware scenario targeting data in S3. The playbook provides a solid framework for incident response on S3.

Additionally, the general “Ransomware Incident Response Playbook” template covers common steps for any ransomware incident, such as:

  1. Acquiring and preserving evidence of the ransomware infection
  2. Containing the incident by isolating affected systems
  3. Identifying and remove the ransomware
  4. Recovering data from backups or known good sources
  5. Conducting post-incident review

While not S3-specific, this playbook provides complementary guidance that could be used in conjunction with the S3 access playbook for an S3 ransomware incident.

The question and response are shown in Figure 6.

Figure 6: Response for S3 ransomware IR playbooks

Figure 6: Response for S3 ransomware IR playbooks

The response provides a high-level overview of the specific playbook that’s being referenced to provide the analyst with context before diving deeper into any single playbook.

Adding functionality to the security chatbot

This sample solution was developed to show the art of the possible. Each customer uses AWS resources to address their business needs in their own way, and security teams must be appropriately equipped to help secure their respective environments. Here are some possible enhancements that you can incorporate into the sample solution to align to your security use-cases and needs.

  1. Incorporate an Amazon DynamoDB table to use as part of reporting interactions tied to a specific event or finding GUID. By incorporating an audit trail, you can tie actions taken by the agent and associated resources to a security event and validate the outcome of the investigation before taking action.
  2. Tuning the backend chatbot agent to query Amazon Linux Security Center’s Common Vulnerabilities and Exposures (CVE) list or MITRE’s CVE list to see which AWS resources might be in scope and send out consolidated messages to resource owners with recommended actions.
  3. Tuning the backend chatbot agent to take natural language requests and respond with detectors or correlation rules for Amazon OpenSearch or query language for custom detections in your security information and event management (SIEM) tool.
  4. Adding a new data source to Athena, such as AWS Config, to provide the analyst with additional capabilities to query AWS resource configuration across the AWS environment that might have been impacted by a security event. For example, if a security finding shows that an S3 bucket has been made public, querying what and when other configuration changes were made to the S3 bucket.
  5. Incorporating multi-agent-orchestration to scale the use of multiple Amazon Bedrock agents that can be tuned towards niche security use cases by respective teams. The chatbot can speak directly to a classifier or controller, which then addresses the user’s natural language request and orchestrates across one or more agents to generate a response. For example, if a user asks which EC2 instances might have been impacted by a security event and which playbook to use to respond, the classifier agent could direct the initial query to the agent in this sample solution. In the same chat window, the analyst could ask if there are any open CVEs for the EC2 instances in scope to get a list of CVEs to address within the AWS account.
  6. For long running Athena queries, you can incorporate an AWS Step Function to the workflow and incorporate a task token to wait for the Athena results to return.

Clean up

If you deployed the security chatbot sample solution by using the Launch Stack button and the console with the CloudFormation template security_genai_chatbot_cfn, do the following to clean up:

  1. In the CloudFormation console for the account and Region where you deployed the solution, choose the SecurityGenAIChatbot stack.
  2. Choose the option to Delete the stack.

If you deployed the solution by using the AWS CDK, run the command cdk destroy --all.

Conclusion

The sample solution demonstrates how you can use task-oriented Amazon Bedrock agents and natural language input to help accelerate investigation and analysis and increase your overall security posture. We provided an example of a sample solution with a user interface that is powered by an Amazon Bedrock agent, which you can extend to add additional task-oriented agents, each with their own instructions, knowledge bases, and models. By extending the use of AI-powered agents, you can help your security team operate more efficiently across multiple security domains within your AWS environment.

The backend for the chatbot to investigate security events uses Security Lake, which normalizes data into Open Cybersecurity Schema Framework (OCSF); as long as the data schema is normalized, the solution can be applied to other data lakes within your AWS environment.

To learn more, see the other posts in this series:

Use the comments section to provide feedback. If you have questions about this post, start a new thread on the Generative AI on AWS re:Post or contact AWS Support.

Madhunika-Reddy-Mikkili

Madhunika Reddy Mikkili

Madhunika is a Data and Machine Learning Engineer at AWS. She is passionate about helping customers achieve their goals using data analytics and machine learning.

Author

Jonathan Nguyen

Jonathan is a Principal Security Solution Architect at AWS. He helps large financial services customers develop a comprehensive security strategy and solutions to meet their security and compliance requirements in AWS.

Harsh Asnani

Harsh Asnani

Harsh is a Machine Learning Engineer at AWS specializing in ML theory, MLOPs, and production generative AI frameworks. His background is in applied data science with a focus on operationalizing AI workloads in the cloud at scale.

Michael Massey

Michael Massey

Michael is a Cloud Application Architect at AWS, where he specializes in building frontend and backend cloud-centered applications. He designs and implements scalable and highly-available solutions and architectures that help customers achieve their business goals.t

Amazon Nova Premier: Our most capable model for complex tasks and teacher for model distillation

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/amazon-nova-premier-our-most-capable-model-for-complex-tasks-and-teacher-for-model-distillation/

Today we’re expanding the Amazon Nova family of foundation models announced at AWS re:Invent with the general availability of Amazon Nova Premier, our most capable model for complex tasks and teacher for model distillation.

Nova Premier joins the existing Amazon Nova understanding models available in Amazon Bedrock. Similar to Nova Lite and Pro, Premier can process input text, images, and videos (excluding audio). With its advanced capabilities, Nova Premier excels at complex tasks that require deep understanding of context, multistep planning, and precise execution across multiple tools and data sources. With a context length of one million tokens, Nova Premier can process extremely long documents or large code bases.

With Nova Premier and Amazon Bedrock Model Distillation, you can create highly capable, cost-effective, and low-latency versions of Nova Pro, Lite, and Micro, for your specific needs. For example, we used Nova Premier to distill Nova Pro for complex tool selection and API calling. The distilled Nova Pro had a 20% higher accuracy for API invocations compared to the base model and consistently matched the performance of the teacher, with the speed and cost benefits of Nova Pro.

Amazon Nova Premier benchmark evaluation
We evaluated Nova Premier on a broad range of benchmarks across text intelligence, visual intelligence, and agentic workflows. Nova Premier is the most capable model in the Nova family as measured across 17 benchmarks as shown in the table below.

Amazon Nova Premier Benchmark Evaluations

Nova Premier is also comparable to the best non-reasoning models in the industry and is equal or better on approximately half of these benchmarks when compared to other models in the same intelligence tier. Details of these evaluations are in the technical report.

Nova Premier is also the fastest and the most cost-effective model in Amazon Bedrock for its intelligence tier. For further details and comparison on pricing, please refer to the Bedrock pricing page.

Nova Premier can also be used as a teacher model for distillation, which means you can transfer its advanced capabilities for a specific use case into smaller, faster, and more efficient models like Nova Pro, Micro, and Lite for production deployments.

Using Amazon Nova Premier
To get started with Nova Premier, you first need to request access to the model in the Amazon Bedrock console. Navigate to Model access in the navigation pane, find Nova Premier, and toggle access.

Console screenshot.

Once you have access, you can use Nova Premier through the Amazon Bedrock Converse API providing in input a list of messages from the user and the assistant. Messages can include text, images, and videos. Here’s an example of a straightforward invocation using the AWS SDK for Python (Boto3):

import boto3
import json

AWS_REGION = "us-east-1"
MODEL_ID = "us.amazon.nova-premier-v1:0"

bedrock_runtime = boto3.client('bedrock-runtime', region_name=AWS_REGION)
messages = [
    {
        "role": "user",
        "content": [
            {
                "text": "Explain the differences between vector databases and traditional relational databases for AI applications."
            }
        ]
    }
]

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=messages
)

response_text = response["output"]["message"]["content"][-1]["text"]

print(response_text)

This example shows how Nova Premier can provide detailed explanations for complex technical questions. But the real power of Premier comes with its ability to handle sophisticated workflows.

Multi-agent collaboration use case
Let’s explore a more complex scenario that showcases how Nova Premier works a multi-agent collaboration architecture for investment research.

The equity research process typically involves multiple stages: identifying relevant data sources for specific investments, retrieving required information from those sources, and synthesizing the data into actionable insights. This process becomes increasingly complex when dealing with different types of financial instruments like stock indices, individual equities, and currencies.

We can build this type of application using multi-agent collaboration in Amazon Bedrock, with Nova Premier powering the supervisor agent that orchestrates the entire workflow. The supervisor agent analyzes the initial query (for example, “What are the emerging trends in renewable energy investments?”), breaks it down into logical steps, determines which specialized subagents to engage, and synthesizes the final response.

For this scenario, I’ve created a system with the following components:

  1. A supervisor agent powered by Nova Premier
  2. Multiple specialized subagents powered by Nova Pro, each focusing on different financial data sources
  3. Tools that connect to financial databases, market analysis tools, and other relevant information sources

Multi-agent architectural diagram

When I submit a query about emerging trends in renewable energy investments, the supervisor agent powered by Nova Premier does the following:

  1. Analyzes the query to determine the underlying topics and sources to cover
  2. Selects the appropriate subagents specific to those topics and sources
  3. Each subagent retrieves their relevant economic indicators, technical analysis, and market sentiment data
  4. The supervisor agent synthesizes this information into a comprehensive report for review by a financial professional

Utilizing Nova Premier in a multi-agent collaboration architecture such as this streamlines the financial professional’s work and helps them formulate their investment analysis faster. The following video provides a visual description of this scenario.

The key advantage of using Nova Premier for the supervisor role is its accuracy in coordinating complex workflows, so that the right data sources are consulted in the optimal sequence and each subagent receives in input the correct information for their work, resulting in higher quality insights.

Multi-agent collaboration with model distillation
Although Nova Premier provides the highest level of accuracy of its family of models, you might want to optimize latency and cost in production environments. This is where the strength of Nova Premier as a teacher model for distillation becomes interesting. Using Amazon Bedrock Model Distillation, we can customize Nova Micro from the results of Nova Premier for this specific investment research use case.

Unlike traditional fine-tuning that requires human feedback and labeled examples, with model distillation you can generate high-quality training data by having a teacher model produce the desired outputs, streamlining the data acquisition process.

Amazon Bedrock Model Distillation diagram

The process to distill a model involves:

  1. Generating synthetic training data by capturing input and output from Nova Premier runs across multiple financial instruments
  2. Using this data as a reference to train a customized version of Nova Micro through custom fine-tuning tools
  3. Evaluating the difference in latency and performance of the customized Micro model
  4. Deploying the customized Micro model as the supervisor agent in production

With Amazon Bedrock, you can further streamline the process and use invocation logs for data preparation. To do that, you need to set the model invocation logging on and set up an Amazon Simple Storage Service (Amazon S3) bucket as the destination for the logs.

Customer voices
Some of our customers had early access to Nova Premier. This is what they shared with us:

“Amazon Nova Premier has been outstanding in its ability to execute interactive analysis workflows, while still being faster and nearly half the cost compared to other leading models in our tests,” said Curtis Allen, Senior Staff Engineer at Slack, a company bringing conversations, apps, and customers together in one place.

“Implementing new solutions built on top of Amazon Nova has helped us with our mission of democratizing finance for all,” said Dev Tagare, Head of AI and Data at Robinhood Markets, a company on a mission to democratize finance for all. “We’re particularly excited about the ability to explore new avenues like complex multi-agent collaborations that are not just highly performing but also cost effective and fast. The intelligence of Nova Premier and what it can transfer to the other models like Nova Micro, Nova Lite, and Nova Pro unlocks multi-agent collaboration at a performance, price, and speed that will make it accessible to everyday customers.”

“Accelerating real-world AI deployments—not just prototypes—requires the ability to build models that are specialized for the unique needs of real world applications,” said Henry Ehrenberg, co-founder of Snorkel AI, a technology company that empowers data scientists and developers to quickly turn data into accurate and adaptable AI applications. “We’re excited to see AWS pushing efficient model customization forward with Amazon Bedrock Model Distillation and Amazon Nova Premier. These new model capabilities have the potential to accelerate our enterprise customers in building production AI applications, including Q&A applications with multimodal data and more.”

Things to know

Nova Premier is available in Amazon Bedrock in the US East (N. Virginia), US East (Ohio), and US West (Oregon) AWS Regions today via cross-Region inference. With Amazon Bedrock, you only pay for what you use. For more information, visit Amazon Bedrock pricing.

Customers in the US can also access Amazon Nova models at https://nova.amazon.com, a website to easily explore our FMs.

Nova Premier is our best teacher for distilling custom variants of Nova Pro, Micro, and Lite, which means you can capture the capabilities offered by Premier in smaller, faster models for production deployment.

Nova Premier includes built-in safety controls to promote responsible AI use, with content moderation capabilities that help maintain appropriate outputs across a wide range of applications.

To get started with Nova Premier, visit the Amazon Bedrock console today. For more information, see the Amazon Nova User Guide and send feedback to AWS re:Post for Amazon Bedrock. Explore the generative AI section of our community.aws site to see how our Builder communities are using Amazon Bedrock in their solutions.

– Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Llama 4 models from Meta now available in Amazon Bedrock serverless

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/llama-4-models-from-meta-now-available-in-amazon-bedrock-serverless/

The newest AI models from Meta, Llama 4 Scout 17B and Llama 4 Maverick 17B, are now available as a fully managed, serverless option in Amazon Bedrock. These new foundation models (FMs) deliver natively multimodal capabilities with early fusion technology that you can use for precise image grounding and extended context processing in your applications.

Llama 4 uses an innovative mixture-of-experts (MoE) architecture that provides enhanced performance across reasoning and image understanding tasks while optimizing for both cost and speed. This architectural approach enables Llama 4 to offer improved performance at lower cost compared to Llama 3, with expanded language support for global applications.

The models were already available on Amazon SageMaker JumpStart, and you can now use them in Amazon Bedrock to streamline building and scaling generative AI applications with enterprise-grade security and privacy.

Llama 4 Maverick 17B – A natively multimodal model featuring 128 experts and 400 billion total parameters. It excels in image and text understanding, making it suitable for versatile assistant and chat applications. The model supports a 1 million token context window, giving you the flexibility to process lengthy documents and complex inputs.

Llama 4 Scout 17B – A general-purpose multimodal model with 16 experts, 17 billion active parameters, and 109 billion total parameters that delivers superior performance compared to all previous Llama models. Amazon Bedrock currently supports a 3.5 million token context window for Llama 4 Scout, with plans to expand in the near future.

Use cases for Llama 4 models
You can use the advanced capabilities of Llama 4 models for a wide range of use cases across industries:

Enterprise applications – Build intelligent agents that can reason across tools and workflows, process multimodal inputs, and deliver high-quality responses for business applications.

Multilingual assistants – Create chat applications that understand images and provide high-quality responses across multiple languages, making them accessible to global audiences.

Code and document intelligence – Develop applications that can understand code, extract structured data from documents, and provide insightful analysis across large volumes of text and code.

Customer support – Enhance support systems with image analysis capabilities, enabling more effective problem resolution when customers share screenshots or photos.

Content creation – Generate creative content across multiple languages, with the ability to understand and respond to visual inputs.

Research – Build research applications that can integrate and analyze multimodal data, providing insights across text and images.

Using Llama 4 models in Amazon Bedrock
To use these new serverless models in Amazon Bedrock, I first need to request access. In the Amazon Bedrock console, I choose Model access from the navigation pane to toggle access to Llama 4 Maverick 17B and Llama 4 Scout 17B models.

Console screenshot.

The Llama 4 models can be easily integrated into your applications using the Amazon Bedrock Converse API, which provides a unified interface for conversational AI interactions.

Here’s an example of how to use the AWS SDK for Python (Boto3) with Llama 4 Maverick for a multimodal conversation:

import boto3
import json
import os

AWS_REGION = "us-west-2"
MODEL_ID = "us.meta.llama4-maverick-17b-instruct-v1:0"
IMAGE_PATH = "image.jpg"


def get_file_extension(filename: str) -> str:
    """Get the file extension."""
    extension = os.path.splitext(filename)[1].lower()[1:] or 'txt'
    if extension == 'jpg':
        extension = 'jpeg'
    return extension


def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

bedrock_runtime = boto3.client(
    service_name="bedrock-runtime",
    region_name=AWS_REGION
)

request_body = {
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "text": "What can you tell me about this image?"
                },
                {
                    "image": {
                        "format": get_file_extension(IMAGE_PATH),
                        "source": {"bytes": read_file(IMAGE_PATH)},
                    }
                },
            ],
        }
    ]
}

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=request_body["messages"]
)

print(response["output"]["message"]["content"][-1]["text"])

This example demonstrates how to send both text and image inputs to the model and receive a conversational response. The Converse API abstracts away the complexity of working with different model input formats, providing a consistent interface across models in Amazon Bedrock.

For more interactive use cases, you can also use the streaming capabilities of the Converse API:

response_stream = bedrock_runtime.converse_stream(
    modelId=MODEL_ID,
    messages=request_body['messages']
)

stream = response_stream.get('stream')
if stream:
    for event in stream:

        if 'messageStart' in event:
            print(f"\nRole: {event['messageStart']['role']}")

        if 'contentBlockDelta' in event:
            print(event['contentBlockDelta']['delta']['text'], end="")

        if 'messageStop' in event:
            print(f"\nStop reason: {event['messageStop']['stopReason']}")

        if 'metadata' in event:
            metadata = event['metadata']
            if 'usage' in metadata:
                print(f"Usage: {json.dumps(metadata['usage'], indent=4)}")
            if 'metrics' in metadata:
                print(f"Metrics: {json.dumps(metadata['metrics'], indent=4)}")

With streaming, your applications can provide a more responsive experience by displaying model outputs as they are generated.

Things to know
The Llama 4 models are available today with a fully managed, serverless experience in Amazon Bedrock in the US East (N. Virginia) and US West (Oregon) AWS Regions. You can also access Llama 4 in US East (Ohio) via cross-region inference.

As usual with Amazon Bedrock, you pay for what you use. For more information, see Amazon Bedrock pricing.

These models support 12 languages for text (English, French, German, Hindi, Italian, Portuguese, Spanish, Thai, Arabic, Indonesian, Tagalog, and Vietnamese) and English when processing images.

To start using these new models today, visit the Meta Llama models section in the Amazon Bedrock User Guide. You can also explore how our Builder communities are using Amazon Bedrock in their solutions in the generative AI section of our community.aws site.

— Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Writer Palmyra X5 and X4 foundation models are now available in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/writer-palmyra-x5-and-x4-foundation-models-are-now-available-in-amazon-bedrock/

One thing we’ve witnessed in recent months is the expansion of context windows in foundation models (FMs), with many now handling sequence lengths that would have been unimaginable just a year ago. However, building AI-powered applications that can process vast amounts of information while maintaining the reliability and security standards required for enterprise use remains challenging.

For these reasons, we’re excited to announce that Writer Palmyra X5 and X4 models are available today in Amazon Bedrock as a fully managed, serverless offering. AWS is the first major cloud provider to deliver fully managed models from Writer. Palmyra X5 is a new model launched today by Writer. Palmyra X4 was previously available in Amazon Bedrock Marketplace.

Writer Palmyra models offer robust reasoning capabilities that support complex agent-based workflows while maintaining enterprise security standards and reliability. Palmyra X5 features a one million token context window, and Palmyra X4 supports a 128K token context window. With these extensive context windows, these models remove some of the traditional constraints for app and agent development, enabling deeper analysis and more comprehensive task completion.

With this launch, Amazon Bedrock continues to bring access to the most advanced models and the tools you need to build generative AI applications with security, privacy, and responsible AI.

As a pioneer in FM development, Writer trains and fine-tunes its industry leading models on Amazon SageMaker HyperPod. With its optimized distributed training environment, Writer reduces training time and brings its models to market faster.

Palmyra X5 and X4 use cases
Writer Palmyra X5 and X4 are designed specifically for enterprise use cases, combining powerful capabilities with stringent security measures, including System and Organization Controls (SOC) 2, Payment Card Industry Data Security Standard (PCI DSS), and Health Insurance Portability and Accountability Act (HIPAA) compliance certifications.

Palmyra X5 and X4 models excel in various enterprise use cases across multiple industries:

Financial services – Palmyra models power solutions across investment banking and asset and wealth management, including deal transaction support, 10-Q, 10-K and earnings transcript highlights, fund and market research, and personalized client outreach at scale.

Healthcare and life science – Payors and providers use Palmyra models to build solutions for member acquisition and onboarding, appeals and grievances, case and utilization management, and employer request for proposal (RFP) response. Pharmaceutical companies use these models for commercial applications, medical affairs, R&D, and clinical trials.

Retail and consumer goods – Palmyra models enable AI solutions for product description creation and variation, performance analysis, SEO updates, brand and compliance reviews, automated campaign workflows, and RFP analysis and response.

Technology – Companies across the technology sector implement Palmyra models for personalized and account-based marketing, content creation, campaign workflow automation, account preparation and research, knowledge support, job briefs and candidate reports, and RFP responses.

Palmyra models support a comprehensive suite of enterprise-grade capabilities, including:

Adaptive thinking – Hybrid models combining advanced reasoning with enterprise-grade reliability, excelling at complex problem-solving and sophisticated decision-making processes.

Multistep tool-calling – Support for advanced tool-calling capabilities that can be used in complex multistep workflows and agentic actions, including interaction with enterprise systems to perform tasks like updating systems, executing transactions, sending emails, and triggering workflows.

Enterprise-grade reliability – Consistent, accurate results while maintaining strict quality standards required for enterprise use, with models specifically trained on business content to align outputs with professional standards.

Using Palmyra X5 and X4 in Amazon Bedrock
As for all new serverless models in Amazon Bedrock, I need to request access first. In the Amazon Bedrock console, I choose Model access from the navigation pane to enable access to Palmyra X5 and Palmyra X4 models.

Console screenshot

When I have access to the models, I can start building applications with any AWS SDKs using the Amazon Bedrock Converse API. The models use cross-Region inference with these inference profiles:

  • For Palmyra X5: us.writer.palmyra-x5-v1:0
  • For Palmyra X4: us.writer.palmyra-x4-v1:0

Here’s a sample implementation with the AWS SDK for Python (Boto3). In this scenario, there is a new version of an existing product. I need to prepare a detailed comparison of what’s new. I have the old and new product manuals. I use the large input context of Palmyra X5 to read and compare the two versions of the manual and prepare a first draft of the comparison document.

import sys
import os
import boto3
import re

AWS_REGION = "us-west-2"
MODEL_ID = "us.writer.palmyra-x5-v1:0"
DEFAULT_OUTPUT_FILE = "product_comparison.md"

def create_bedrock_runtime_client(region: str = AWS_REGION):
    """Create and return a Bedrock client."""
    return boto3.client('bedrock-runtime', region_name=region)

def get_file_extension(filename: str) -> str:
    """Get the file extension."""
    return os.path.splitext(filename)[1].lower()[1:] or 'txt'

def sanitize_document_name(filename: str) -> str:
    """Sanitize document name."""
    # Remove extension and get base name
    name = os.path.splitext(filename)[0]
    
    # Replace invalid characters with space
    name = re.sub(r'[^a-zA-Z0-9\s\-\(\)\[\]]', ' ', name)
    
    # Replace multiple spaces with single space
    name = re.sub(r'\s+', ' ', name)
    
    # Strip leading/trailing spaces
    return name.strip()

def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

def generate_comparison(client, document1: bytes, document2: bytes, filename1: str, filename2: str) -> str:
    """Generate a markdown comparison of two product manuals."""
    print(f"Generating comparison for {filename1} and {filename2}")
    try:
        response = client.converse(
            modelId=MODEL_ID,
            messages=[
                {
                    "role": "user",
                    "content": [
                        {
                            "text": "Please compare these two product manuals and create a detailed comparison in markdown format. Focus on comparing key features, specifications, and highlight the main differences between the products."
                        },
                        {
                            "document": {
                                "format": get_file_extension(filename1),
                                "name": sanitize_document_name(filename1),
                                "source": {
                                    "bytes": document1
                                }
                            }
                        },
                        {
                            "document": {
                                "format": get_file_extension(filename2),
                                "name": sanitize_document_name(filename2),
                                "source": {
                                    "bytes": document2
                                }
                            }
                        }
                    ]
                }
            ]
        )
        return response['output']['message']['content'][0]['text']
    except Exception as e:
        raise Exception(f"Error generating comparison: {str(e)}")

def main():
    if len(sys.argv) < 3 or len(sys.argv) > 4:
        cmd = sys.argv[0]
        print(f"Usage: {cmd} <manual1_path> <manual2_path> [output_file]")
        sys.exit(1)

    manual1_path = sys.argv[1]
    manual2_path = sys.argv[2]
    output_file = sys.argv[3] if len(sys.argv) == 4 else DEFAULT_OUTPUT_FILE
    paths = [manual1_path, manual2_path]

    # Check each file's existence
    for path in paths:
        if not os.path.exists(path):
            print(f"Error: File does not exist: {path}")
            sys.exit(1)

    try:
        # Create Bedrock client
        bedrock_runtime = create_bedrock_runtime_client()

        # Read both manuals
        print("Reading documents...")
        manual1_content = read_file(manual1_path)
        manual2_content = read_file(manual2_path)

        # Generate comparison directly from the documents
        print("Generating comparison...")
        comparison = generate_comparison(
            bedrock_runtime,
            manual1_content,
            manual2_content,
            os.path.basename(manual1_path),
            os.path.basename(manual2_path)
        )

        # Save comparison to file
        with open(output_file, 'w') as f:
            f.write(comparison)

        print(f"Comparison generated successfully! Saved to {output_file}")

    except Exception as e:
        print(f"Error: {str(e)}")
        sys.exit(1)

if __name__ == "__main__":
    main()

To learn how to use Amazon Bedrock with AWS SDKs, browse the code samples in the Amazon Bedrock User Guide.

Things to know
Writer Palmyra X5 and X4 models are available in Amazon Bedrock today in the US West (Oregon) AWS Region with cross-Region inference. For the most up-to-date information on model support by Region, refer to the Amazon Bedrock documentation. For information on pricing, visit Amazon Bedrock pricing.

These models support English, Spanish, French, German, Chinese, and multiple other languages, making them suitable for global enterprise applications.

Using the expansive context capabilities of these models, developers can build more sophisticated applications and agents that can process extensive documents, perform complex multistep reasoning, and handle sophisticated agentic workflows.

To start using Writer Palmyra X5 and X4 models today, visit the Writer model section in the Amazon Bedrock User Guide. You can also explore how our Builder communities are using Amazon Bedrock in their solutions in the generative AI section of our community.aws site.

Let us know what you build with these powerful new capabilities!

— Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Amazon introduces SWE-PolyBench, a multilingual benchmark for AI Coding Agents

Post Syndicated from Christian Bock original https://aws.amazon.com/blogs/devops/amazon-introduces-swe-polybench-a-multi-lingual-benchmark-for-ai-coding-agents/

Coding agents powered by large language models have shown impressive capabilities in software engineering tasks, but evaluating their performance across diverse programming languages and real-world scenarios remains challenging. This led to a recent explosion in benchmark creation to assess the coding effectiveness of said systems in controlled environments. In particular, SWE-Bench which measures the performance of systems in the context of GitHub issues has spurred the development of capable coding agents resulting in over 50 leaderboard submissions, thereby becoming the de-facto standard for coding agent benchmarking. Despite its significant impact as a pioneering benchmark, SWE-Bench, and in particular its “verified” subset, also shows some limitations. It contains only Python repositories, the majority of tasks are bug fixes, and at over 45% of all tasks, the Django repository is significantly over-represented.

Today, Amazon introduces SWE-PolyBench, the first industry benchmark to evaluate AI coding agents’ ability to navigate and understand complex codebases, introducing rich metrics to advance AI performance in real-world scenarios. SWE-PolyBench contains over 2,000 curated issues in four languages. In addition, it contains a stratified subset of 500 issues (SWE-PolyBench500) for the purpose of rapid experimentation. SWE-PolyBench evaluates the performance of AI coding agents through a comprehensive set of metrics: pass rates across different programming languages and task complexity levels, along with precision and recall measurements for code/file context identification. These evaluation metrics can help the community address challenges in understanding how well AI coding agents can navigate through and comprehend complex codebases

The leaderboard is accessible here. The SWE-PolyBench dataset is available on Hugging Face and the paper at arxiv. Evaluations can be run using the SWE-PolyBench codebase.

Below, we describe the key features, characteristics, and the creation process of our dataset alongside the new evaluation metrics, and performance of open source agents from our experiments.

Key features of SWE-PolyBench at a glance

  1. Multi-Language Support: Java (165 tasks), JavaScript (1017 tasks), TypeScript (729 tasks), and Python (199 tasks).
  2. Extensive Dataset: 2110 instances from 21 repositories ranging from web frameworks to code editors and ML tools, on the same scale as SWE-Bench full with more repository.
  3. Task Variety: Includes bug fixes, feature requests, and code refactoring.
  4. Faster Experimentation: SWE-PolyBench500 is a stratified subset for efficient experimentation.
  5. Leaderboard: A leaderboard with a rich set of metrics for transparent benchmarking.

Building a comprehensive dataset

The creation of SWE-PolyBench involved a data collection and filtering process designed to ensure the quality and relevance of the benchmark tasks. SWE-Bench, a benchmark for Python code generation, evaluates agents on real-world programming tasks by utilizing GitHub issues and their corresponding code and test modifications. We extended the SWE-Bench data acquisition pipeline to support 3 additional languages besides Python and used it to gather and process coding challenges from real-world repositories as shown in Figure 1.

A flowchart diagram showing a software development process. It starts with an issue (#3039) and pull request (#3147) on the left, goes through a metadata filter in the middle, then splits into a runtime setup and testing phase on the right. The testing phase feeds into a test-based filter at the end. The diagram includes icons for programming languages like JavaScript, TypeScript, Python, and Java.

Figure 1: Overview of the SWE-PolyBench data generation pipeline, illustrating the process of collecting, filtering, and validating coding tasks.

The data acquisition pipeline collects pull requests (PRs) that close issues from popular repositories across Java, JavaScript, TypeScript, and Python. These PRs undergo filtering and are set up in containerized environments for consistent test execution. The process categorizes tests as fail-to-pass (F2P) or pass-to-pass (P2P) based on their outcomes before and after patch application. Only PRs with at least one F2P test are included in the final dataset, ensuring that each task represents a meaningful coding challenge. This streamlined approach results in a dataset that closely mimics real-world coding scenarios, providing a robust foundation for evaluating AI coding assistants.

Dataset characteristics

When constructing SWE-PolyBench, we aimed to collect GitHub issues that represent diverse programming scenarios: issues involving modifications across multiple code files and spanning different task categories (such as bug fixes, feature requests, and refactoring). Tables 1 and 2 provide descriptive statistics on the composition and complexity of SWE-PolyBench full (PB) and SWE-PolyBench500 (PB500). To offer a point of reference, we compare these statistics with those of SWE-Bench (SWE) and SWE-Bench verified (SWEv). Tasks in SWE-PolyBench require on average more files to be modified and more nodes to be changed, which indicates that they have higher complexity and are closer to tasks in real-world projects. The distribution of tasks is also more diverse, in particular for SWE-PolyBench500.

A comparison table showing statistics for different software benchmarks (SWE-PolyBench, SWE-PolyBench500, SWE-Bench, and SWE-Bench verified). The table has two main sections: Modified Files showing average changes across programming languages (Python, Java, JavaScript, TypeScript), and Task Category distribution showing percentages for Bug Fix, Feature Request, Refactoring, and Miscellaneous tasks

A detailed table comparing dataset complexity across different programming languages and benchmarks (SWE, SWEv, PB, and PB500). The table shows statistics for syntax tree node changes, divided into two main sections: Node Change Category percentages (None, Function only, Class only, Mixed) and Node Change Count averages (Function, Class, Number of Nodes). The highest values in each column are shown in bold, with notable variations across Python, Java, JavaScript, and TypeScript implementations.

New evaluation metrics

To comprehensively evaluate AI coding assistants, SWE-Polybench introduces multiple new metrics in addition to the pass rate. The pass rate is the proportion of tasks successfully solved as measured by the generated patch passing all relevant tests. It is the primary metric for assessing coding agent performance, but it doesn’t provide a complete picture of an agent’s capabilities. In particular, it doesn’t give much information on an agent’s ability to navigate and understand complex code repositories. SWE-PolyBench introduces a new set of metrics based on Concrete Syntax Tree (CST) node analysis and the established file-level localization metric:

  1. File-level Localization: assesses the agent’s ability to identify the correct files that need to be modified within a repository. Let us assume that we would need to modify file.py to solve our problem. If our coding agent implements a change in any other file, it would receive a file retrieval score of 0.
  2. CST Node-level Retrieval: evaluates the agent’s ability to identify specific code structures that require changes. It uses the Concrete Syntax Tree (CST) representation of the code to measure how accurately the agent can locate the exact functions or classes that need modification.
A side-by-side comparison showing two Git version control diffs. Each diff shows a line being removed (in red, prefixed with '-') where my_var equals 3, and a line being added (in green, prefixed with '+') where my_var equals 2. Above the diffs are connected dots in different colors (green, pink, blue, and yellow) representing Git commit history visualization.

Figure 2: Illustration of CST node changes.

In Figure 2, we see a change in class node A materialized by a change in its initialization function on the left path starting from the file node. In contrast to the first change, the change in class B is considered a function node change as it doesn’t impact class construction.

Let us assume the change that would solve our problem is the change in the __init__ function. If our coding agent implements the change in my_func, it receives both a class and function node retrieval score of 0.

By combining pass rate assessment with both file-level and CST node-level retrieval metrics, SWE-PolyBench offers a detailed evaluation of AI coding assistants’ capabilities in real-world scenarios. This approach provides deeper insights into how well agents navigate and comprehend complex codebases, going beyond simple task completion to assess their understanding of code structure and organization.

Performance of open-source coding agents

Key Findings

  1. Language Proficiency: Python is the strongest language for all agents, likely due to its prevalence in training data and existing benchmarks.
  2. Complexity Challenges: Performance degrades as task complexity increases, particularly when modifications to 3 or more files are required.
  3. Task Specialization: Different agents show strengths in various task categories (bug fixes, feature requests, refactoring).
  4. Context Importance: The informativeness of problem statements impacts success rates across all agents (refer to Figure 5 of the appendix paper for details about this analysis).

Many existing open-source agents are designed primarily for Python. Adapting them to work for all four languages of SWE-PolyBench required adjusting test execution commands, modifying parsing mechanisms, and adapting containerization strategies for each language. We adapted and evaluated three open-source agents on SWE-PolyBench. The aforementioned adjustments are reflected by the added “-PB” suffix to the original agent names.

Two radar charts comparing three AI models: Aider-PB Sonnet 3.5, Agentless-PB Sonnet 3.5, and SWE-agent-PB Sonnet 3.5. The left chart shows performance across programming languages (Java, JavaScript, TypeScript, Python). The right chart displays performance in different coding styles (Functional only, Single Function, All, Mixed, No nodes, Single Class, Class only). Each model is represented by a different colored line, with Aider-PB generally showing the highest performance across categories.

Figure 3: Performance of coding agents across programming languages and task complexities, highlighting strengths and areas for improvement.

Figure 3 provides a visual representation of agent performance across different dimensions:

  • Language Proficiency: The left side of the chart shows that all three agents perform best in Python, with significantly lower pass rates in other languages. This highlights the current bias towards Python in many coding agents and their underlying large language models.
  • Task Complexity: The right side of the chart illustrates how performance degrades as task complexity increases. Agents show higher pass rates for tasks involving single class or function changes, but struggle with tasks requiring modifications to multiple classes or functions and in instances where both class and function changes are required.

This comprehensive view of agent performance underscores the value of SWE-PolyBench in identifying specific strengths and weaknesses of different coding assistants, paving the way for targeted improvements in future iterations.

In addition to these insights, the evaluation revealed interesting patterns across different task categories as shown in Table 2. The performance data across bug fixes, feature requests, and refactoring tasks reveals varying strengths among AI coding assistants. The performance on bug fixing tasks is relatively consistent. There is more variability between different agents and between multiple runs of a given agent for feature request tasks and refactoring tasks.

Table 3 showing average pass rates with standard error by task category for three agents: Agentless-PB, SWE-Agent-PB, and Aider-PB. The task categories are Bug Fix, Feature Request, and Refactoring. Aider-PB has the highest pass rates for Bug Fix (13.8) and Feature Request (15.1), while SWE-Agent-PB leads in Refactoring (16.1). Standard errors are provided for each value.

Join the SWE-PolyBench community

SWE-PolyBench and its evaluation framework are publicly available. This open approach invites the global developer community to build upon this work and advance the field of AI-assisted software engineering. As coding agents continue to evolve, benchmarks like SWE-PolyBench play a crucial role in ensuring they can meet the diverse needs of real-world software development across multiple programming languages and task types.

Explore SWE-PolyBench today and contribute to the future of AI-powered software engineering!

Resources

Authors

Christian Bock

Christian Bock is an Applied Scientist at Amazon Web Services working on AI for code.

Laurent Callot

Laurent Callot is a Principal Applied Scientist at Amazon Web Services leading teams creating AI agents for software development.

Luca Franceschi

Luca Franceschi is an Applied Scientist at Amazon Web Services working on ML models to improve the efficiency of AI agents for code generation.

Woo Jung Kim

Woo Jung Kim is an applied scientist at Amazon Web Services. He is developing an AI agentic tool designed to improve developer’s productivity.

Shihab Rashid

Shihab Rashid is an Applied Scientist at Amazon Web Services working on agentic AI for code generation with a focus on multi agent systems.

Prabhu Teja

Prabhu Teja is an Applied Scientist at Amazon Web Services. Prabhu works on LLM assisted code generation with a focus on natural language interaction.

Simon Valentin

Simon Valentin is an Applied Scientist at Amazon Web Services working on AI for code.

Martin Wistuba

Martin Wistuba is a senior applied scientist at Amazon Web Services. As part of Amazon Q Developer, he is helping developers to write more code in less time.

Giovanni Zappella

Giovanni Zappella is a Principal Applied Scientist working on the creations of intelligent agents for code generation. While at Amazon he also contributed to the creation of new algorithms for Continual Learning, AutoML and recommendations systems.

Yuan Zhuang

Yuan Zhuang is an Applied Scientist at Amazon Web Services working on AI agents for code generation.

Announcing AWS Security Reference Architecture Code Examples for Generative AI

Post Syndicated from Ievgeniia Ieromenko original https://aws.amazon.com/blogs/security/announcing-aws-security-reference-architecture-code-examples-for-generative-ai/

Amazon Web Services (AWS) is pleased to announce the release of new Security Reference Architecture (SRA) code examples for securing generative AI workloads. The examples include two comprehensive capabilities focusing on secure model inference and RAG implementations, covering a wide range of security controls and best practices for AWS generative AI services.

These new code examples are available in the AWS SRA Examples Repository and include ready-to-deploy CloudFormation templates for implementing detective security controls such as network segmentation, identity management, encryption, prompt injection detection, and logging and monitoring. The solutions align with the AWS SRA Design Guidance page and demonstrate our commitment to helping customers secure their generative AI implementations.

Customers can get started with these examples by following the implementation instructions for each solution in the AWS SRA Examples Repository Solutions GenAI page. Additional documentation and implementation guidance is available in the AWS SRA Design Guidance Generative AI Architecture Deep Dive.

AWS strives to continuously provide security solutions that help customers meet their security architecture needs. Customers can reach out to the team by submitting an issue in the code repository.

If you have feedback about this post, submit comments in the Comments section below.

Ievgeniia Ieromenko

Ievgeniia Ieromenko

Ievgeniia a Security Engineer at AWS, focusing on cloud security architecture and best practices. She is a key contributor to the AWS Security Reference Architecture GitHub repository, helping customers implement secure cloud environments.

Liam Schneider

Liam Schneider

Liam is a Sr. Security Engineer with deep experience in cloud and application security, focused on reducing risk, improving system resilience, and aligning security with business needs. Liam has a strong background in compliance, team leadership, and building secure, scalable solutions across complex environments. He is known for practical, effective approaches to modern security challenges in both enterprise and cloud-first organizations.

Justin Kontny

Justin Kontny

Justin is a Sr. Security Engineer at AWS who combines his passion for software development with expertise in cloud security. He focuses on transforming security from a barrier to a business enabler through innovative AI-driven automation. When not pushing the boundaries of cloud security, Justin enjoys time with his children and being active outdoors.

Introducing Amazon Nova Sonic: Human-like voice conversations for generative AI applications

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-amazon-nova-sonic-human-like-voice-conversations-for-generative-ai-applications/

Voice interfaces are essential to enhance customer experience in different areas such as customer support call automation, gaming, interactive education, and language learning. However, there are challenges when building voice-enabled applications.

Traditional approaches in building voice-enabled applications require complex orchestration of multiple models, such as speech recognition to convert speech to text, language models to understand and generate responses, and text-to-speech to convert text back to audio.

This fragmented approach not only increases development complexity but also fails to preserve crucial linguistic context such as tone, prosody, and speaking style that are essential for natural conversations. This can affect conversational AI applications that need low latency and nuanced understanding of verbal and non-verbal cues for fluid dialog handling and natural turn-taking.

To streamline the implementation of speech-enabled applications, today we are introducing Amazon Nova Sonic, the newest addition to the Amazon Nova family of foundation models (FMs) available in Amazon Bedrock.

Amazon Nova Sonic unifies speech understanding and generation into a single model that developers can use to create natural, human-like conversational AI experiences with low latency and industry-leading price performance. This integrated approach streamlines development and reduces complexity when building conversational applications.

Its unified model architecture delivers expressive speech generation and real-time text transcription without requiring a separate model. The result is an adaptive speech response that dynamically adjusts its delivery based on prosody, such as pace and timbre, of input speech.

When using Amazon Nova Sonic, developers have access to function calling (also known as tool use) and agentic workflows to interact with external services and APIs and perform tasks in the customer’s environment, including knowledge grounding with enterprise data using Retrieval-Augmented Generation.

At launch, Amazon Nova Sonic provides robust speech understanding for American and British English across various speaking styles and acoustic conditions, with additional languages coming soon.

Amazon Nova Sonic is developed with responsible AI at the forefront of innovation, featuring built-in protections for content moderation and watermarking.

Amazon Nova Sonic in action
The scenario for this demo is a contact center in the telecommunication industry. A customer reaches out to improve their subscription plan, and Amazon Nova Sonic handles the conversation.

With tool use, the model can interact with other systems and use agentic RAG with Amazon Bedrock Knowledge Bases to gather updated, customer-specific information such as account details, subscription plans, and pricing info.

The demo shows streaming transcription of speech input and displays streaming speech responses as text. The sentiment of the conversation is displayed in two ways: a time chart illustrating how it evolves, and a pie chart representing the overall distribution. There’s also an AI insights section providing contextual tips for a call center agent. Other interesting metrics shown in the web interface are the overall talk time distribution between the customer and the agent, and the average response time.

During the conversation with the support agent, you can observe through the metrics and hear in the voices how customer sentiment improves.

The video includes an example of how Amazon Nova Sonic handles interruptions smoothly, stopping to listen and then continuing the conversation in a natural way.

Now, let’s explore how you can integrate voice capabilities in your applications.

Using Amazon Nova Sonic
To get started with Amazon Nova Sonic, you first need to toggle model access in the Amazon Bedrock console, similar to how you would enable other FMs. Navigate to the Model access section of the navigation pane, find Amazon Nova Sonic under the Amazon models, and enable it for your account.

Amazon Bedrock provides a new bidirectional streaming API (InvokeModelWithBidirectionalStream) to help you implement real-time, low-latency conversational experiences on top of the HTTP/2 protocol. With this API, you can stream audio input to the model and receive audio output in real time, so that the conversation flows naturally.

You can use Amazon Nova Sonic with the new API with this model ID: amazon.nova-sonic-v1:0

After the session initialization, where you can configure inference parameters, the model operate through an event-driven architecture on both the input and output streams.

There are three key event types in the input stream:

System prompt – To set the overall system prompt for the conversation

Audio input streaming – To process continuous audio input in real-time

Tool result handling – To send the result of tool use calls back to the model (after tool use is requested in the output events)

Similarly, there are three groups of events in the output streams:

Automatic speech recognition (ASR) streaming – Speech-to-text transcript is generated, containing the result of realtime speech recognition.

Tool use handling – If there are a tool use events, they need to be handled using the information provided here, and the results sent back as input events.

Audio output streaming – To play output audio in real-time, a buffer is needed, because Amazon Nova Sonic model generates audio faster than real-time playback.

You can find examples of using Amazon Nova Sonic in the Amazon Nova model cookbook repository.

Prompt engineering for speech
When crafting prompts for Amazon Nova Sonic, your prompts should optimize content for auditory comprehension rather than visual reading, focusing on conversational flow and clarity when heard rather than seen.

When defining roles for your assistant, focus on conversational attributes (such as warm, patient, concise) rather than text-oriented attributes (detailed, comprehensive, systematic). A good baseline system prompt might be:

You are a friend. The user and you will engage in a spoken dialog exchanging the transcripts of a natural real-time conversation. Keep your responses short, generally two or three sentences for chatty scenarios.

More generally, when creating prompts for speech models, avoid requesting visual formatting (such as bullet points, tables, or code blocks), voice characteristic modifications (accent, age, or singing), or sound effects.

Things to know
Amazon Nova Sonic is available today in the US East (N. Virginia) AWS Region. Visit Amazon Bedrock pricing to see the pricing models.

Amazon Nova Sonic can understand speech in different speaking styles and generates speech in expressive voices, including both masculine-sounding and feminine-sounding voices, in different English accents, including American and British. Support for additional languages will be coming soon.

Amazon Nova Sonic handles user interruptions gracefully without dropping the conversational context and is robust to background noise. The model supports a context window of 32K tokens for audio with a rolling window to handle longer conversations and has a default session limit of 8 minutes.

The following AWS SDKs support the new bidirectional streaming API:

Python developers can use this new experimental SDK that makes it easier to use the bidirectional streaming capabilities of Amazon Nova Sonic. We’re working to add support to the other AWS SDKs.

I’d like to thank Reilly Manton and Chad Hendren, who set up the demo with the contact center in the telecommunication industry, and Anuj Jauhari, who helped me understand the rich landscape in which speech-to-speech models are being deployed.

To learn more, these articles that enter into the details of how to use the new bidirectional streaming API with compelling demos:

Whether you’re creating customer service solutions, language learning applications, or other conversational experiences, Amazon Nova Sonic provides the foundation for natural, engaging voice interactions. To get started, visit the Amazon Bedrock console today. To learn more, visit the Amazon Nova section of the user guide.

– Danilo


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

AWS Weekly Roundup: Omdia recognition, Amazon Bedrock RAG evaluation, International Women’s Day events, and more (March 24, 2025)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-omdia-recognition-amazon-bedrock-rag-evaluation-international-womens-day-events-and-more-march-24-2025/

As we celebrate International Women’s Day (IWD) this March, I had the privilege of attending the ‘Women in Tech’ User Group meetup in Shenzhen last weekend. I was inspired to see over 100 women in tech from different industries come together to discuss AI ethics from a female perspective. Together, we explored strategies such as reducing gender bias in AI systems and promoting diverse representation in model training data. In the AWS Cloud Lab, participants used Amazon Bedrock with large language models (LLMs) to generate rose bloom videos, which was the most popular part of this meetup.

These gatherings are crucial to our efforts to engage more women in AI technology exploration and development, and to help make sure that the generative AI era evolves without gender bias. The collaborative spirit and technical curiosity displayed throughout the event is further proof that diverse teams truly build inclusive and effective solutions.

Speaking of vibrant community engagement, I also had the honor of presenting at Kubernetes Community Day (KCD) Beijing 2025 this weekend. The enthusiasm Omdia Universe: Cloud Container Management & Services 2024-25 reportfor container technologies was remarkable, with nearly 300 developers gathering to share experiences and best practices. During my keynote introducing the DoEKS project from Amazon Web Services (AWS), I was struck by the depth of interest in managed Kubernetes services. The audience’s questions revealed how widely adopted services such as Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS) have become among Chinese developers building mission-critical applications.This strong community interest aligns perfectly with findings from the Omdia Universe: Cloud Container Management & Services 2024–25 report. In this comprehensive evaluation of container management solutions hosted on public clouds, AWS was recognized as a Leader. The report specifically highlights that AWS offers “widest range of options for working with Kubernetes or its own container management service, across cloud, edge, and on-premises environments.” You can read the full report about AWS offerings to learn more about our comprehensive container portfolio and how we’re helping builders deploy scalable, reliable containerized applications.

Last Week’s launches

In addition to the inspiring community events, here are some AWS launches that caught my attention.

Amazon Q Business browser extension gets upgrades – The Amazon Q Business browser extension now features significant enhancements designed to streamline browser-based tasks. Users gain access to their company’s indexed knowledge alongside web content, direct PDF support within the browser, image file attachment capabilities, and controls to remove irrelevant attachments from conversation context. The expanded context window accommodates larger web pages and more detailed prompts, resulting in more helpful responses. For advanced needs, the extension offers seamless transition to the full Amazon Q Business web experience with access to Actions and Amazon Q Apps. Review the Enhancing web browsing with Amazon Q Business in the documentation for detailed setup instructions and feature descriptions to learn more about this announcement.

Amazon Bedrock RAG evaluation is now generally available – Offering comprehensive assessment of both Bedrock Knowledge Bases and custom Retrieval Augmented Generation (RAG) systems through LLM-as-a-judge methodology. The service evaluates retrieval quality and end-to-end generation with metrics for relevance, correctness, and hallucination detection, and the newly added support for custom RAG pipeline evaluations lets you bring your own input-output pairs and retrieved contexts directly into the evaluation job, along with new citation precision metrics and Amazon Bedrock Guardrails integration for more flexible RAG system optimization. To learn more, visit the Amazon Bedrock Evaluations page and What is Amazon Bedrock? in the documentation.

Amazon Nova expands Tool Choice options for Converse API – We’ve enhanced Amazon Nova with expanded Tool Choice capabilities for the Converse API, giving developers more flexibility in building sophisticated AI applications. This update allows models to determine when to use tools to fulfill user requests more effectively. Learn more in the announcement about expands Tool Choice options.

Amazon Bedrock Guardrails adds policy-based enforcement for responsible AI – Our builders can now enforce responsible AI policies at scale with Amazon Bedrock Guardrails’ new AWS Identity and Access Management (IAM) policy-based enforcement capabilities. This feature helps you to specify required guardrails through IAM policies using the bedrock:GuardrailIdentifiercondition key, so that all model inference calls comply with your organization’s AI safety standards. When your teams make Amazon Bedrock Invoke or Converse API calls, requests are automatically rejected if they don’t include the mandated guardrails, providing consistent protection against undesirable content, sensitive information exposure, and model hallucinations. Refer to the Set up permissions to use Guaidrails for content filtering in the technical documentation and the Amazon Bedrock Guardrails product page to learn more about the announcement about policy based enforcement for responsible AI.

Next generation of Amazon Connect released – We’ve launched the next generation of Amazon Connect, featuring AI-powered interactions designed to strengthen customer relationships and improve business outcomes. This major update brings enhanced agent experiences, smarter customer interactions, and deeper operational insights to contact centers of all sizes. Learn more from the new launch post in the AWS Contact Center Blog.

Amazon Redshift Serverless introduces Current and Trailing release tracks – Amazon Redshift Serverless now offers two release tracks to give users more control over their update cadence. The Current track delivers the most up-to-date certified release with the latest features and security updates, while the Trailing track remains on the previous certified release. This dual-track approach allows organizations to validate new releases on select workgroups before implementing them across production environments. Users can easily switch between tracks through the Amazon Redshift console, providing the flexibility to balance innovation with stability for mission-critical workloads. This capability is available in all AWS Regions where Amazon Redshift Serverless is offered. Refer to Tracks for Amazon Redshift provisioned cluster and serverless work groups to learn more about the Current and Trailing tracks in Amazon Redshift Serverless.

AWS WAF now supports URI fragment field matching – AWS WAF has expanded its capability to include URI fragment field matching, allowing security teams to create rules that inspect and match against the fragment portion of URLs. This enhancement enables more precise security controls for web applications that use URI fragments to identify specific sections within pages. Security professionals can now implement more targeted protections, such as restricting access to sensitive page elements, detecting suspicious navigation patterns, and enhancing bot mitigation by analyzing fragment usage patterns characteristic of automated attacks. This feature is available in all AWS Regions where AWS WAF is supported. For more information about URI field for matching, visit the AWS WAF Developer Guide.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS.

Other AWS news

Here are some other additional projects and blog posts that you might find interesting.

Build your generative AI skills at AWS Gen AI Lofts – AWS has established more than 10 global hubs offering training and networking for developers and startups in 2025, where you can gain practical, hands-on experience with the latest AI technologies. These revamped spaces feature dedicated zones where you can participate in workshops on prompt engineering, foundation model (FM) selection, and implementing AI in production environments. If you’re near San Francisco, New York, Tokyo, or other major tech hubs with AWS Gen AI Lofts, stop by to access these free resources and accelerate your generative AI development skills. Check out all of the AWS Gen AI Loft locations and events and to read 5 ways to build your AI skills on AWS Gen AI Loft to learn more.

AWS Lambda‘s architecture for billions of asynchronous invocations – A recent technical article reveals how AWS Lambda handles massive scale through sophisticated engineering approaches. The Lambda asynchronous invocation path employs multiple queuing strategies, consistent hashing for intelligent partitioning, and shuffle-sharding techniques to minimize noisy neighbor effects. The system relies on key observability metrics (AsyncEventReceived, AsyncEventAge, and AsyncEventDropped) to maintain optimal performance. These architectural decisions enable Lambda to process tens of trillions of monthly invocations across 1.5 million active customers while providing reliable scalability and performance isolation. For details read Handling billions of invocations – best practices from AWS Lambda in the AWS computing blog.

AWS is reducing prices by more than 11% for its high-memory U7i instances across all Regions and pricing models. The reduction applies to four instances: u7i-12tb.224xlarge, u7in-16tb.224xlarge, u7in-24tb.224xlarge, and u7in-32tb.224xlarge. The new On-Demand pricing, which covers shared, dedicated, and host tenancy options is retroactive, to March 1, 2025. For new Savings Plan purchases, pricing is effective immediately.

Create your AWS Builder ID and reserve your alias – Builder ID is a universal login credential that gives you access beyond the AWS Management Console to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

From community.aws
Here are some of my favorite posts from community.aws.

Model Context Protocol (MCP): why it matters – The recently introduced Model Context Protocol (MCP) creates a standardized way for AI applications to communicate with multiple FMs using consistent prompts and tools.

Build serverless GenAI Apps faster with Amazon Q Developer CLI agent – Discover how Amazon Q Developer CLI Agent revolutionizes cloud development by building a complete serverless generative AI application in minutes instead of days.

Automating code reviews with Amazon Q and GitHub actions – A new developer tutorial demonstrates how to integrate Amazon Q Developer with GitHub Actions to automatically analyze pull requests and provide AI-powered code feedback.

DeepSeek on AWS – A new technical guide demonstrates how to deploy DeepSeek’s powerful open-source AI models on AWS infrastructure. The tutorial provides step-by-step instructions for setting up these cutting-edge models using Amazon SageMaker, Amazon Elastic Compute Cloud (Amazon EC2) instances with GPUs, or through integration with Amazon Bedrock. The guide covers optimization techniques, sample applications, and best practices for balancing performance with cost efficiency.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events.

Empowering Futures – Women Leading the Way in Tech and Non-Tech Careers – Whether you’re here to expand your professional circle, learn about the AWS Cloud or gain wisdom from inspiring speakers, this event has something for everyone. This is a public event open to everyone in the Seattle area—for free—on March 27, 2025.

AWS at KubeCon + CloudNativeCon London 2025 – Join us at KubeCon London on April 1 – April 4 , at Excel booth S300 for live product demonstrations that help you simplify Kubernetes operations, optimize costs and performance, harness the power of artificial learning and machine learning (AI/ML), and build scalable platform strategies.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Betty

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

AWS Pi Day 2025: Data foundation for analytics and AI

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-pi-day-data-foundation-for-analytics-and-ai/

Every year on March 14 (3.14), AWS Pi Day highlights AWS innovations that help you manage and work with your data. What started in 2021 as a way to commemorate the fifteenth launch anniversary of Amazon Simple Storage Service (Amazon S3) has now grown into an event that highlights how cloud technologies are transforming data management, analytics, and AI.

This year, AWS Pi Day returns with a focus on accelerating analytics and AI innovation with a unified data foundation on AWS. The data landscape is undergoing a profound transformation as AI emerges in most enterprise strategies, with analytics and AI workloads increasingly converging around a lot of the same data and workflows. You need an easy way to access all your data and use all your preferred analytics and AI tools in a single integrated experience. This AWS Pi Day, we’re introducing a slate of new capabilities that help you build unified and integrated data experiences.

The next generation of Amazon SageMaker: The center of all your data, analytics, and AI
At re:Invent 2024, we introduced the next generation of Amazon SageMaker, the center of all your data, analytics, and AI. SageMaker includes virtually all the components you need for data exploration, preparation and integration, big data processing, fast SQL analytics, machine learning (ML) model development and training, and generative AI application development. With this new generation of Amazon SageMaker, SageMaker Lakehouse provides you with unified access to your data and SageMaker Catalog helps you to meet your governance and security requirements. You can read the launch blog post written by my colleague Antje to learn more details.

Core to the next generation of Amazon SageMaker is SageMaker Unified Studio, a single data and AI development environment where you can use all your data and tools for analytics and AI. SageMaker Unified Studio is now generally available.

SageMaker Unified Studio facilitates collaboration among data scientists, analysts, engineers, and developers as they work on data, analytics, AI workflows, and applications. It provides familiar tools from AWS analytics and artificial intelligence and machine learning (AI/ML) services, including data processing, SQL analytics, ML model development, and generative AI application development, into a single user experience.

SageMaker Unified Studio

SageMaker Unified Studio also brings selected capabilities from Amazon Bedrock into SageMaker. You can now rapidly prototype, customize, and share generative AI applications using foundation models (FMs) and advanced features such as Amazon Bedrock Knowledge Bases, Amazon Bedrock Guardrails, Amazon Bedrock Agents, and Amazon Bedrock Flows to create tailored solutions aligned with your requirements and responsible AI guidelines all within SageMaker.

Last but not least, Amazon Q Developer is now generally available in SageMaker Unified Studio. Amazon Q Developer provides generative AI powered assistance for data and AI development. It helps you with tasks like writing SQL queries, building extract, transform, and load (ETL) jobs, and troubleshooting, and is available in the Free tier and Pro tier for existing subscribers.

You can learn more about SageMaker Unified Studio in this recent blog post written by my colleague Donnie.

During re:Invent 2024, we also launched Amazon SageMaker Lakehouse as part of the next generation of SageMaker. SageMaker Lakehouse unifies all your data across Amazon S3 data lakes, Amazon Redshift data warehouses, and third-party and federated data sources. It helps you build powerful analytics and AI/ML applications on a single copy of your data. SageMaker Lakehouse gives you the flexibility to access and query your data in-place with Apache Iceberg–compatible tools and engines. In addition, zero-ETL integrations automate the process of bringing data into SageMaker Lakehouse from AWS data sources such as Amazon Aurora or Amazon DynamoDB and from applications such as Salesforce, Facebook Ads, Instagram Ads, ServiceNow, SAP, Zendesk, and Zoho CRM. The full list of integrations is available in the SageMaker Lakehouse FAQ.

Building a data foundation with Amazon S3
Building a data foundation is the cornerstone of accelerating analytics and AI workloads, enabling organizations to seamlessly manage, discover, and utilize their data assets at any scale. Amazon S3 is the world’s best place to build a data lake, with virtually unlimited scale, and it provides the essential foundation for this transformation.

I’m always astonished to learn about the scale at which we operate Amazon S3: It currently holds over 400 trillion objects, exabytes of data, and processes a mind-blowing 150 million requests per second. Just a decade ago, not even 100 customers were storing more than a petabyte (PB) of data on S3. Today, thousands of customers have surpassed the 1 PB milestone.

Amazon S3 stores exabytes of tabular data, and it averages over 15 million requests to tabular data per second. To help you reduce the undifferentiated heavy lifting when managing your tabular data in S3 buckets, we announced Amazon S3 Tables at AWS re:Invent 2024. S3 Tables are the first cloud object store with built-in support for Apache Iceberg. S3 tables are specifically optimized for analytics workloads, resulting in up to threefold faster query throughput and up to tenfold higher transactions per second compared to self-managed tables.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse  Amazon S3 Tables now integrate with Amazon SageMaker Lakehouse, making it easy for you to access S3 Tables from AWS analytics services such as Amazon Redshift, Amazon Athena, Amazon EMR, AWS Glue, and Apache Iceberg–compatible engines such as Apache Spark or PyIceberg. SageMaker Lakehouse enables centralized management of fine-grained data access permissions for S3 Tables and other sources and consistently applies them across all engines.

For those of you who use a third-party catalog, have a custom catalog implementation, or only need basic read and write access to tabular data in a single table bucket, we’ve added new APIs that are compatible with the Iceberg REST Catalog standard. This enables any Iceberg-compatible application to seamlessly create, update, list, and delete tables in an S3 table bucket. For unified data management across all of your tabular data, data governance, and fine-grained access controls, you can also use S3 Tables with SageMaker Lakehouse.

To help you access S3 Tables, we’ve launched updates in the AWS Management Console. You can now create a table, populate it with data, and query it directly from the S3 console using Amazon Athena, making it easier to get started and analyze data in S3 table buckets.

The following screenshot shows how to access Athena directly from the S3 console.

S3 console : create table with AthenaWhen I select Query tables with Athena or Create table with Athena, it opens the Athena console on the correct data source, catalog, and database.

S3 Tables in Athena

Since re:Invent 2024, we’ve continued to add new capabilities to S3 Tables at a rapid pace. For example, we added schema definition support to the CreateTable API and you can now create up to 10,000 tables in an S3 table bucket. We also launched S3 Tables into eight additional AWS Regions, with the most recent being Asia Pacific (Seoul, Singapore, Sydney) on March 4, with more to come. You can refer to the S3 Tables AWS Regions page of the documentation to get the list of the eleven Regions where S3 Tables are available today.

Amazon S3 Metadata—announced during re:Invent 2024— has been generally available since January 27. It’s the fastest and easiest way to help you discover and understand your S3 data with automated, effortlessly-queried metadata that updates in near real time. S3 Metadata works with S3 object tags. Tags help you logically group data for a variety of reasons, such as to apply IAM policies to provide fine-grained access, specify tag-based filters to manage object lifecycle rules, and selectively replicate data to another Region. In Regions where S3 Metadata is available, you can capture and query custom metadata that is stored as object tags. To reduce the cost associated with object tags when using S3 Metadata, Amazon S3 reduced pricing for S3 object tagging by 35 percent in all Regions, making it cheaper to use custom metadata.

AWS Pi Day 2025
Over the years, AWS Pi Day has showcased major milestones in cloud storage and data analytics. This year, the AWS Pi Day virtual event will feature a range of topics designed for developers and technical decision-makers, data engineers, AI/ML practitioners, and IT leaders. Key highlights include deep dives, live demos, and expert sessions on all the services and capabilities I discussed in this post.

By attending this event, you’ll learn how you can accelerate your analytics and AI innovation. You’ll learn how you can use S3 Tables with native Apache Iceberg support and S3 Metadata to build scalable data lakes that serve both traditional analytics and emerging AI/ML workloads. You’ll also discover the next generation of Amazon SageMaker, the center for all your data, analytics, and AI, to help your teams collaborate and build faster from a unified studio, using familiar AWS tools with access to all your data whether it’s stored in data lakes, data warehouses, or third-party or federated data sources.

For those looking to stay ahead of the latest cloud trends, AWS Pi Day 2025 is an event you can’t miss. Whether you’re building data lakehouses, training AI models, building generative AI applications, or optimizing analytics workloads, the insights shared will help you maximize the value of your data.

Tune in today and explore the latest in cloud data innovation. Don’t miss the opportunity to engage with AWS experts, partners, and customers shaping the future of data, analytics, and AI.

If you missed the virtual event on March 14, you can visit the event page at any time—we will keep all the content available on-demand there!

— seb


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Accelerate analytics and AI innovation with the next generation of Amazon SageMaker

Post Syndicated from G2 Krishnamoorthy original https://aws.amazon.com/blogs/big-data/accelerate-analytics-and-ai-innovation-with-the-next-generation-of-amazon-sagemaker/

At AWS re:Invent 2024, we announced the next generation of Amazon SageMaker, the center for all your data, analytics, and AI. Amazon SageMaker brings together widely adopted AWS machine learning (ML) and analytics capabilities and addresses the challenges of harnessing organizational data for analytics and AI through unified access to tools and data with governance built in. It enables teams to securely find, prepare, and collaborate on data assets and build analytics and AI applications through a single experience, accelerating the path from data to value.

At the core of the next generation of Amazon SageMaker is Amazon SageMaker Unified Studio, a single data and AI development environment where you can find and access your organization’s data and act on it using the best tool for the job across virtually any use case. We are excited to announce the general availability of SageMaker Unified Studio.

In this post, we explore the benefits of SageMaker Unified Studio and how to get started.

Benefits of SageMaker Unified Studio

SageMaker Unified Studio brings together the functionality and tools from existing AWS Analytics and AI/ML services, including Amazon EMR, AWS Glue, Amazon Athena, Amazon Redshift, Amazon Bedrock, and Amazon SageMaker AI. From within the unified studio, you can discover data and AI assets from across your organization, then work together in projects to securely build and share analytics and AI artifacts, including data, models, and generative AI applications. Governance features including fine-grained access control are built into SageMaker Unified Studio using Amazon SageMaker Catalog to help you meet enterprise security requirements across your entire data estate.

Unified access to your data is provided by Amazon SageMaker Lakehouse, a unified, open, and secure data lakehouse built on Apache Iceberg open standards. Whether your data is stored in Amazon Simple Storage Service (Amazon S3) data lakes, Redshift data warehouses, or third-party and federated data sources, you can access it from one place and use it with Iceberg-compatible engines and tools. In addition, SageMaker Lakehouse now integrates with Amazon S3 Tables, the first cloud object store with native Apache Iceberg support, so you can use SageMaker Lakehouse to create, query, and process S3 Tables efficiently using various analytics engines in SageMaker Unified Studio as well as Iceberg-compatible engines like Apache Spark and PyIceberg.

Capabilities from Amazon Bedrock are now generally available in SageMaker Unified Studio, allowing you to rapidly prototype, customize, and share generative AI applications in a governed environment. Users have an intuitive interface to access high-performing foundation models (FMs) in Amazon Bedrock, including the Amazon Nova model series, and the ability to create Agents, Flows, Knowledge Bases, and Guardrails with a few clicks.

Amazon Q Developer, the most capable generative AI assistant for software development, can be used within SageMaker Unified Studio to streamline tasks across the data and AI development lifecycle, including code authoring, SQL generation, data discovery, and troubleshooting.

A new integrated way of working

The general availability of SageMaker Unified Studio represents another meaningful step in our journey to offer our customers a streamlined way to work with their data, whether for analytics or AI. Many of our customers have told us that you are building data-driven applications to guide business decisions, improve agility, and drive innovation, but that these applications are complex to build because they require collaboration across teams and the integration of data and tools. Not only is it time consuming for users to learn multiple development experiences, but because data, code, and other development artifacts are stored separately, it is challenging for users to understand how they interact with each other and to use them cohesively. Configuring and governing access is also a cumbersome manual process. To overcome these hurdles, many organizations are building bespoke integrations between services, tools, and homegrown access management systems. However, what you need is the flexibility to adopt the best services for your use case while empowering your data teams with a unified development experience.

“When we build data-driven applications for our customers, we want a unified platform where the technologies work together in an integrated way. Amazon SageMaker Unified Studio streamlines our solution delivery processes through comprehensive analytics capabilities, a unified studio experience, and a lakehouse that integrates data management across data warehouses and data lakes. Amazon SageMaker Unified Studio reduces the time-to-value for our customers’ data projects by up to 40%, helping us with our mission to accelerate our customers’ digital transformation journey.”

—Akihiro Suzue, Head of Solutions Sector, NTT DATA; Yuji Shono, Senior Manager, Apps & Data Technology Department, NTT DATA; Yuki Saito, Manager, Digital Success Solutions Division, NTT DATA

Millions of organizations trust AWS and utilize our comprehensive set of purpose-built analytics, AI/ML, and generative AI capabilities to power data-driven applications without compromising on performance, scale, or cost. Our goal for the next generation of Amazon SageMaker, including SageMaker Unified Studio, is to make data and AI workers more productive by providing access to all your data and tools in a single development environment.

Building from a single data and AI development environment

Let’s explore a common business challenge: increasing revenue through better lead generation. Consider an organization implementing an intelligent digital assistant on their website to engage with customers—a process that traditionally requires multiple tools and data sources. With SageMaker Unified Studio, this entire process can now be carried out within a single data and AI development environment.

First, the data team uses the generative AI playground within SageMaker Unified Studio to quickly evaluate and select the best model for their customer interactions. They then create a project to house the tools and resources necessary for their use case and use Amazon Bedrock within the project to build and deploy a sophisticated virtual assistant that quickly begins qualifying leads through their website.

To identify the most promising opportunities, the team develops a segmentation strategy. The data engineer asks Amazon Q Developer to identify datasets that contain lead data and uses zero-ETL integrations to bring the data into SageMaker Lakehouse. The data analyst then discovers it and creates a comprehensive view of their market. They use the SQL query editor to build out marketing segments, which they then write back to SageMaker Lakehouse, where they are available to other team members.

Finally, the data scientist accesses the same dataset, which they use to train and deploy an automated lead scoring model using tools available from SageMaker AI. During the model development phase, they use Amazon Q Developer’s inline code authoring and troubleshooting capabilities to efficiently write error free-code in their JupyterLab notebook. The final model provides sales teams with the highest-value opportunities, which they can visualize in a business intelligence dashboard and take action on immediately.

Reducing time-to-value in a unified environment

What is remarkable about this example is that entire process happens in one integrated environment. Without SageMaker Unified Studio, the team would have had to work with multiple data sources, tools, and services, spending time learning multiple development environments, creating resources shares, and manually configuring access controls. The data engineer and data analyst would have worked in various data warehouses, data lakes, and analytics tools, the data scientist would have worked in an ML studio and notebook environment, and the application builder in a generative AI tool. Now, they’re able to build and collaborate with their data and tools available in one experience, dramatically reducing time-to-value.

That’s why we’re so excited about the next generation of Amazon SageMaker and the general availability of SageMaker Unified Studio. We believe that by putting everything you need for analytics and AI in one place, you can solve complex end-to-end problems more efficiently and get to innovative outcomes faster than ever before.

Getting started with SageMaker Unified Studio

To learn more, check out the following resources:


About the authors

G2 Krishnamoorthy is VP of Analytics, leading AWS data lake services, data integration, Amazon OpenSearch Service, and Amazon QuickSight. Prior to his current role, G2 built and ran the Analytics and ML Platform at Facebook/Meta, and built various parts of the SQL Server database, Azure Analytics, and Azure ML at Microsoft.
Rahul Pathak is VP of Relational Database Engines, leading Amazon Aurora, Amazon Redshift, and Amazon QLDB. Prior to his current role, he was VP of Analytics at AWS, where he worked across the entire AWS database portfolio. He has co-founded two companies, one focused on digital media analytics and the other on IP-geolocation.
Helping us help you: Practical applications of AI in the SOC

Post Syndicated from Conner Goldstein original https://blog.rapid7.com/2025/03/11/helping-us-help-you-practical-applications-of-ai-in-the-soc/

Helping us help you: Practical applications of AI in the SOC

Security teams can be understandably hesitant to integrate artificial intelligence (AI) into incident response workflows. A single mistaken action could lead to widespread disruption, monetary loss, or reputational harm. Meanwhile, attackers  are increasingly leveraging AI to enhance the scale and sophistication of their operations. According to former CISA chief, Jen Easterly, “[it’s] not just teaching cyber bad guys new tricks — it’s also making it easier for anyone to become a bad guy.”

This escalation in AI-driven threats contributes to a more complex attack landscape, intensifying pressures on security teams already grappling with limited resources, and an ever-increasing volume of alerts. As a result, the risks of ignoring AI now outweigh the risks of embracing it.

Whether or not you’re a customer of Rapid7’s managed security offerings, it’s worth understanding how AI is already transforming security operations today – not as a vague promise of the future, but as a real, tangible advantage in the fight against cyber threats. Rapid7 has been at the forefront of this shift. Last summer, my colleague Laura Ellis detailed in her blog post how Rapid7 first infused AI into our MDR workflows; and just a few weeks ago Kelcey Morgan outlined some of the ways AI is essential to integrate into SOC workflows. Now, we’re taking it even further, and customers are seeing the impact firsthand.

Below, we explore some of the key ways AI is actively driving secure, efficient, and transparent outcomes within Rapid7’s global Security Operations Center (SOC), and how customers of our Managed Threat Complete service are benefitting from these advancements firsthand.

AI-Powered Auto-Triage

Currently Available

What it is: AI-driven models that automatically analyze and close low-risk alerts, allowing analysts to focus on real threats. Using a layered ensemble approach, these machine learning models harness the collective expertise of Rapid7’s MDR analysts to instantly identify and resolve low-risk security alerts, as well as highlight potentially dangerous alerts. This allows our analysts to quickly identify and respond to the greatest threats to our customers’ networks.

Real-world impact: In a recent incident, a customer’s MDR environment generated over 8,000 benign alerts in a short time span. While Rapid7’s 24x7x365 SOC could have manually processed them, our AI models accurately triaged and identified them as benign without human intervention – freeing up analysts to focus on actual threats.

Why it matters: AI allows our SOC to reallocate human expertise to more complex investigations, reducing fatigue and response times while improving detection accuracy. Customers get faster, higher-quality security outcomes without being overwhelmed by false positives.

NEW: AI Alert Triage Decisioning Transparency

What it is: Complete transparency into alerts closed by the SOC with the assistance of AI-powered auto-triage capabilities.

Real-world impact: Transparency in auto-triage decisions is crucial for maintaining trust and security oversight. If an alert for potentially malicious certutil activity is closed as benign via our AI-powered Alert Triage capability, customers can review what input was relevant in driving the AI model’s rationale. Likewise, if a PowerShell execution on a critical server is escalated, they can see exactly why, based on factors like anomalous command sequences or credential access attempts. This visibility eliminates black-box decision-making, allowing security teams to confidently verify and act on AI-driven decisions.

Why it matters: Without visibility into auto-triage decisions, security teams risk over-reliance on automation without understanding its reasoning – potentially leading to missed threats or unnecessary escalations. By ensuring transparency, Rapid7’s AI-Powered Alert Triage empowers customers with insight into decision logic, helping them maintain security control, verify actions, and confidently respond to threats. This aligns with Rapid7’s TRISM Framework, which emphasizes trust in AI-driven security environments to ensure customers can harness AI without compromising visibility or control.

Helping us help you: Practical applications of AI in the SOC

AI-Generated Incident Reports

Currently Available

What it is: AI-powered automation that initiates detailed incident reports, including root cause analysis and impacted systems, arming the SOC with foundational information to recommend next steps.

Real-world impact: Traditionally, analysts manually compile post-incident reports, a process that can take hours. With AI-driven automation, incident summaries are generated in minutes, pulling in relevant data, impact analysis, and remediation insights automatically. Analysts then validate and refine these reports before sharing them with customers.

Why it matters: Customers get faster, more actionable insights following security incidents, reducing downtime and allowing for quicker remediation. AI doesn’t replace expert analysis – it enhances it, giving security teams the information they need to act decisively.

AI-Powered MDR SOC Assistant

Currently Available

What it is: AI-driven assistants that provide real-time recommendations, enrichment, and decision support for Rapid7 SOC analysts during investigations.

Real-world impact: When Rapid7 SOC analysts investigate a suspicious event, AI automatically enriches it with historical attack patterns, threat intelligence, and behavioral context to provide suggested next steps. If similar cases exist in other environments, AI identifies patterns and highlights potential threats before they escalate.

Why it matters:The AI-Powered MDR SOC Assistant acts as an on-demand expert for Rapid7’s MDR analysts that speeds up investigations, helping analysts make data-driven decisions, and ensures no critical detail is overlooked. This translates to faster investigation and response times for customers.

AI-Driven Threat Detections

Currently Available

What it is: AI identifies subtle patterns and anomalies that might indicate emerging threats before they trigger traditional detection rules.

Real-world impact: AI-driven analytics help uncover a multi-stage attack in its earliest phase by detecting an unusual combination of process executions across multiple endpoints. Analysts are alerted to the activity and mitigate the threat before it can escalate into a full-blown breach.

Why it matters: Traditional security tools rely on known signatures or predefined rules. AI allows for earlier detection of nuanced threats, helping customers stay ahead of sophisticated attacks that might otherwise go unnoticed. Learn more about these detections.

The time to embrace AI is now

AI-powered SOC automations are no longer futuristic ideas – they are practical, real-world solutions already making security teams faster, smarter, and more effective. The question is no longer “Should we leverage AI?” but rather “How can we leverage AI responsibly and effectively within our Security Operations teams and workflows?”

As we outlined in our previous blog, the introduction of AI into security workflows is not about replacing humans – it’s about empowering them. At Rapid7, we’ve seen firsthand how AI can reduce noise, accelerate investigations, and help security teams stay ahead of evolving threats – and we’re just getting started.

Fortunately, security teams don’t have to navigate this new frontier alone. With Rapid7’s AI-enhanced MDR services, customers get the best of both worlds – AI-powered efficiency combined with expert human oversight. Whether through AI-Powered Alert Triage, AI-Generated Incident Reports, or AI-assisted investigation and threat detection, the message is clear: embracing AI isn’t just about adopting new technology – it’s about accelerating outcomes in an increasingly unpredictable digital world.

If you’re ready to explore how AI helps us to help you bolster your security operations, let’s talk.

Unlock the power of optimization in Amazon Redshift Serverless

Post Syndicated from Ricardo Serafim original https://aws.amazon.com/blogs/big-data/unlock-the-power-of-optimization-in-amazon-redshift-serverless/

Amazon Redshift Serverless automatically scales compute capacity to match workload demands, measuring this capacity in Redshift Processing Units (RPUs). Although traditional scaling primarily responds to query queue times, the new AI-driven scaling and optimization feature offers a more sophisticated approach by considering multiple factors including query complexity and data volume. Intelligent scaling addresses key data warehouse challenges by preventing both over-provisioning of resources for performance and under-provisioning to save costs, particularly for workloads that fluctuate based on daily patterns or monthly cycles.

Amazon Redshift serverless now offers enhanced flexibility in configuring workgroups through two primary methods. Users can either set a base capacity, specifying the baseline RPUs for query execution, with options ranging from 8 to 1024 RPUs and each RPU providing 16 GB of memory, or they can opt for the price-performance target. Amazon Redshift Serverless AI-driven scaling and optimization can adapt more precisely to diverse workload requirements and employs intelligent resource management, automatically adjusting resources during query execution for optimal performance. Consider using AI-driven scaling and optimization if your current workload requires 32 to 512 base RPUs. We don’t recommend using this feature for less than 32 base RPU or more than 512 base RPU workloads.

In this post, we demonstrate how Amazon Redshift Serverless AI-driven scaling and optimization impacts performance and cost across different optimization profiles.

Options in AI-driven scaling and optimization

Amazon Redshift Serverless AI-driven scaling and optimization offers an intuitive slider interface, letting you balance price and performance goals. You can select from five optimization profiles, ranging from Optimized for Cost to Optimized for Performance, as shown in the following diagram. Your slider position determines how Amazon Redshift allocates resources and implements AI-driven scaling and optimizations, to achieve your desired price-performance target.

Sliding bar

The slider offers the following options:

  1. Optimized for Cost (1)
    • Prioritizes cost savings over performance
    • Allocates minimum resources in favor of saving on costs
    • Best for workloads where performance isn’t time-critical
  2. Cost-Balanced (25)
    • Balances towards cost savings while maintaining reasonable performance
    • Allocates moderate resources
    • Suitable for mixed workloads with some flexibility in query time
  3. Balanced (50)
    • Provides equal emphasis on cost efficiency and performance
    • Allocates optimal resources for most use cases
    • Ideal for general-purpose workloads
  4. Performance-Balanced (75)
    • Favors performance while maintaining some cost control
    • Allocates additional resources when needed
    • Suitable for workloads requiring consistently fast query elapsed time
  5. Optimized for Performance (100)
    • Maximizes performance regardless of cost
    • Provides maximum available resources
    • Best for time-critical workloads requiring fastest possible query delivery

Which workloads to consider for AI-driven scaling and optimizations

The Amazon Redshift Serverless AI-driven scaling and optimization capabilities can be applied to almost every analytical workload. Amazon Redshift will assess and apply optimizations according to your price-performance target—cost, balance, or performance.

Most analytical workloads operate on millions or even billions of rows and generate aggregations and complex calculations. These workloads have high variability for query patterns and number of queries. The Amazon Redshift Serverless AI-driven scaling and optimization will improve the price, performance, or both because it learns the patterns (the repeatability of your workload) and will allocate more resources towards performance improvements if you’re performance-focused or fewer resources if you’re cost-focused.

Cost-effectiveness of AI-driven scaling and optimization

To effectively determine the effectiveness of Amazon Redshift Serverless AI-driven scaling and optimization we need to be able to measure your current state of price-performance. We encourage you to measure your current price-performance by using sys_query_history to calculate the total elapsed time of your workload and note the start time and end time. Then use sys_serverless_usage to calculate the cost. You can use the query from the Amazon Redshift documentation and add the same start and end times. This will establish your current price performance, and now you have a baseline to compare against.

If such measurement isn’t practical because your workloads are continuously running and it’s impractical for you to determine a fixed start and end time, then another way is to compare holistically, check your month over month cost, check your user sentiment towards performance, towards system stability, improvements in data delivery, or reduction in overall monthly processing times.

Benchmark conducted and results

We evaluated the optimization options using the TPCDS 3TB dataset from the AWS Labs GitHub repository (amazon-redshift-utils). We deployed this dataset across three Amazon Redshift Serverless workgroups configured as Optimized for Cost, Balanced, and Optimized for Performance. To create a realistic reporting environment, we configured three Amazon Elastic Compute Cloud (Amazon EC2) instances with JMeter (one per endpoint) and ran 15 selected TPCDS queries concurrently for approximately 1 hour, as shown in the following screenshot.

We disabled the result cache to make sure Amazon Redshift Serverless ran all queries directly, providing accurate measurements. This setup helped us capture authentic performance characteristics across each optimization profile. Also, we designed our test environment without setting the Amazon Redshift Serverless workgroup max capacity parameter—a key configuration that controls the maximum RPUs available to your data warehouse. By removing this limit, we could clearly showcase how different configurations affect scaling behavior in our test endpoints.

Jmeter

Our comprehensive test plan included running each of the 15 queries 355 times, generating 5,325 queries per test cycle. The AI-driven scaling and optimization needs multiple iterations to identify patterns and optimize RPUs, so we ran this workload 10 times. Through these repetitions, the AI learned and adapted its behavior, processing a total of 53,250 queries throughout our testing period.

The testing revealed how the AI-driven scaling and optimization system adapts and optimizes performance across three distinct configuration profiles: Optimized for Cost, Balanced, and Optimized for Performance.

Queries and elapsed time

Although we ran the same core workload repeatedly, we used variable parameters in JMeter to generate different values for the WHERE clause conditions. This approach created similar but not identical workloads, introducing natural variations that showed how the system handles real-world scenarios with varying query patterns.

Our elapsed time analysis demonstrates how each configuration achieved its performance objectives, as shown by the average consumption metrics for each endpoint, as shown in the following screenshot.

Average Elapsed Time per Endpoint

The results matched our expectations: the Optimized for Performance configuration delivered significant speed improvements, running queries approximately two times as the Balanced configuration and four times as the Optimized for Cost setup.

The following screenshots show the elapsed time breakdown for each test.

Optimized for Cost - Elapsed Time Balanced - Elapsed Time Optimized for Performance - Elapsed Time

The following screenshot shows tenth and final test iteration demonstrates distinct performance differences across configurations.

Per Configuration - Elapsed Time

To clarify more, we categorized our query elapsed times into three groups:

  • Short queries – Less than 10 seconds
  • Medium queries – From 10 seconds to 10 minutes
  • Long queries: More than 10 minutes

Considering our last test, the analysis shows:

Duration per configuration Optimized for Cost Balanced Optimized for Performance
Short queries (<10 sec) 1488 1743 3290
Medium queries (10 sec – 10 min) 3633 3579 2035
Long queries (>10 min) 204 3 0
TOTAL 5325 5325 5325

The configuration’s capacity directly impacts query elapsed time. The Optimized for Cost configuration limits resources to save money, resulting in longer query times, making it best suited for workloads that aren’t time critical, where cost savings are prioritized. The Balanced configuration provides moderate resource allocation, striking a middle ground by effectively handling medium-duration queries and maintaining reasonable performance for short queries while nearly eliminating long-running queries. In contrast, the Optimized for Performance configuration allocates more resources, which increases costs but delivers faster query results, making it best for latency-sensitive workloads where query speed is critical.

Capacity used during the tests

Our comparison of the three configurations reveals how Amazon Redshift Serverless AI-driven scaling and optimization technology adapts resource allocation to meet user expectations. The monitoring showed both Base RPU variations and distinct scaling patterns across configurations—scaling up aggressively for faster performance or maintaining lower RPUs to optimize costs.

The Optimized for Cost configuration starts at 128 RPUs and increases to 256 RPUs after three tests. To maintain cost-efficiency, this setup limits the maximum RPU allocation during scaling, even when facing query queuing.

In the following table, we can observe the costs for this Optimized for Cost configuration.

Test# Starting RPUs Scaled up to Cost incurred
1 128 1408  $254.17
2 128 1408  $258.39
3 128 1408  $261.92
4 256 1408  $245.57
5 256 1408  $247.11
6 256 1408  $257.25
7 256 1408  $254.27
8 256 1408  $254.27
9 256 1408  $254.11
10 256 1408  $256.15

The strategic RPU allocation by Amazon Redshift Serverless helps optimize costs, as demonstrated in tests 3 and 4, where we observed significant cost savings. This is shown in the following graph.

Optimized for Cost - Cost Average

Although the optimization for cost changed the base RPU, the balanced configuration didn’t change the base RPUs but scaled up to 2176, further than the 1408 RPUs that were the maximum used by the cost optimization setup. The following table shows the figures for the Balanced configuration.

Test# Starting RPUs Scaled up to Cost incurred
1 192 2176  $261.48
2 192 2112  $270.90
3 192 2112  $265.26
4 192 2112  $260.20
5 192 2112  $262.12
6 192 2112  $253.18
7 192 2112  $272.80
8 192 2112  $272.80
9 192 2112  $263.72
10 192 2112  $243.28

The Balanced configuration, averaging $262.57 per test, delivered significantly better performance while costing only 3% more than the Optimized for Cost configuration, which averaged $254.32 per test. As demonstrated in the previous section, this performance advantage is evident in the elapsed time comparisons. The following graph shows the costs for the Balanced configuration.

Balanced - Cost Average

As expected from the Optimized for Performance configuration, the usage of resources was higher to attend the high performance. In this configuration, we can also observe that after two tests, the engine adapted itself to start with a higher number of RPUs to attend the queries faster.

Test# Starting RPUs Scaled Up to Cost incurred
1 512 2753  $295.07
2 512 2327  $280.29
3 768 2560  $333.52
4 768 2991  $295.36
5 768 2479  $308.72
6 768 2816  $324.08
7 768 2413  $300.45
8 768 2413  $300.45
9 768 2107  $321.07
10 768 2304  $284.93

Despite a 19% cost increase in the third test, most subsequent tests remained below the $304.39 average cost.

Optimized for Performance - Cost Average

The Optimized for Performance configuration maximizes resource usage to achieve faster query times, prioritizing speed over cost efficiency.

The final cost-performance analysis reveals compelling results:

  • The Balanced configuration delivered twofold better performance while costing only 3.25% more than the Optimized for Cost setup
  • The Optimized for Performance configuration achieved fourfold faster elapsed time with a 19.39% cost increase compared to the Optimized for Cost option.

The following chart illustrates our cost-performance findings:

Average Billing and Elapsed Time per Endpoint

It’s important to note that these results reflect our specific test scenario. Each workload has unique characteristics, and the performance and cost differences between configurations might vary significantly in other use cases. Our findings serve as a reference point rather than a universal benchmark. Additionally, we didn’t test two intermediate configurations available in Amazon Redshift Serverless: one between Optimized for Cost and Balanced, and another between Balanced and Optimized for Performance.

Conclusion

The test results demonstrate the effectiveness of Amazon Redshift Serverless AI-driven scaling and optimization across different workload requirements. These findings highlight how Amazon Redshift Serverless AI-driven scaling and optimization can help organizations find their ideal balance between cost and performance. Although our test results serve as a reference point, each organization should evaluate their specific workload requirements and price-performance targets. The flexibility of five different optimization profiles, combined with intelligent resource allocation, enables teams to fine-tune their data warehouse operations for optimal efficiency.

To get started with Amazon Redshift Serverless AI-driven scaling and optimization, we recommend:

  1. Establishing your current price-performance baseline
  2. Identifying your workload patterns and requirements
  3. Testing different optimization profiles with your specific workloads
  4. Monitoring and adjusting based on your results

By using these capabilities, organizations can achieve better resource utilization while meeting their specific performance and cost objectives.

Ready to optimize your Amazon Redshift Serverless workloads? Visit the AWS Management Console today to create your own Amazon Redshift Serverless AI-driven scaling and optimization to start exploring the different optimization profiles. For more information, check out our documentation on Amazon Redshift Serverless AI-driven scaling and optimization, or contact your AWS account team to discuss your specific use case.


About the Authors

Ricardo Serafim Ricardo Serafim is a Senior Analytics Specialist Solutions Architect at AWS. He has been helping companies with Data Warehouse solutions since 2007.

Milind Oke Milind Oke is a Data Warehouse Specialist Solutions Architect based out of New York. He has been building data warehouse solutions for over 15 years and specializes in Amazon Redshift.

Andre HassAndre Hass is a Senior Technical Account Manager at AWS, specialized in AWS Data Analytics workloads. With more than 20 years of experience in databases and data analytics, he helps customers optimize their data solutions and navigate complex technical challenges. When not immersed in the world of data, Andre can be found pursuing his passion for outdoor adventures. He enjoys camping, hiking, and exploring new destinations with his family on weekends or whenever an opportunity arises.