We’re excited to announce that Workers will soon be able to send outbound requests through a mutually authenticated channel via mutual TLS authentication!
When making outbound requests from a Worker, TLS is always used on the server side, so that the client can validate that the information is being sent to the right destination. But in the same way, the server may want to authenticate the client to ensure that the request is coming from an authorized client. This two-way street of authentication is called Mutual TLS. In this blog, we’re going to talk through the importance of mutual TLS authentication, what it means to use mutual TLS within Workers, and how in a few months you’ll be able to use it to send information through an authenticated channel — adding a layer of security to your application!
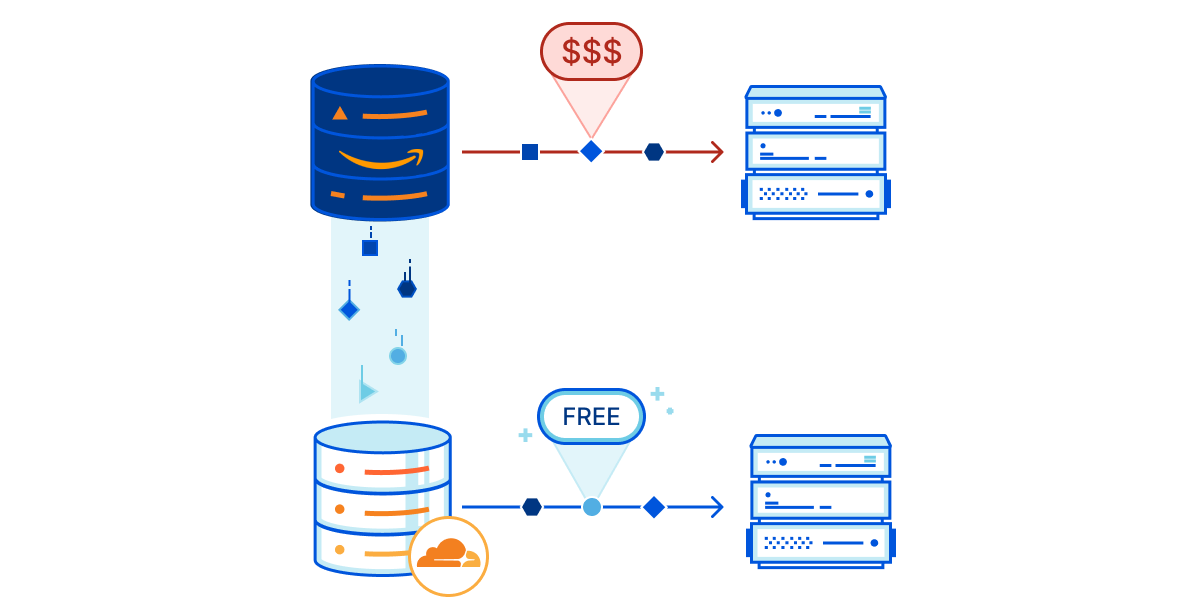
mTLS between Cloudflare and an Origin
Mutual TLS authentication works by having a server validate the client certificate against a CA. If the validation passes then the server knows that it’s the right client and will let the request go through. If the validation fails or if a client certificate is not presented then the server can choose to drop the request.
Today, customers use mTLS to secure connections between Cloudflare and an origin — this is done through a product called Authenticated Origin Pull. Once a customer enables it, Cloudflare starts serving a client certificate on all outgoing requests. This is either a Cloudflare managed client certificate or it can be one uploaded by the customer. When enabled, Cloudflare will present this certificate when connecting to an origin. The origin should then check the client certificate to see if it’s the one that it expects to see. If it is then the request will go through. If it’s the wrong client certificate or is not included then the origin can choose to drop the request.
Doing this brings a big security boost because it allows the origin to only accept traffic from Cloudflare and drop any unexpected external traffic.
Digging up problems with dogfooding
Today, many Cloudflare services are built on Cloudflare Workers — it’s the secret sauce we use to continuously ship fast, reliable products to our customers. Internally, we might have one Cloudflare account that runs multiple services, with each service deployed on an individual Worker.
Whenever one service needs to talk to another, the fetch() function is used to request or send information. This can be object data that we send to upstream providers, it can be a read or write to a database, or service to service communication. In most regards, the information that’s going to the origin is sensitive and requires a layer of authentication. Without proper authentication, any client would be able to access the data, removing a layer of security.
Implementing service to service authentication
Today, there are a few ways that you can set up service to service authentication, if you’re building on Workers.
One way to set up service authentication is to use Authenticated Origin Pull. Authenticated Origin Pull allows customers to implement mutual TLS between Cloudflare and an origin by attaching a client certificate and private key to a domain or hostname, so that all outbound requests include a client certificate. The origin can then check this certificate to see whether the request came from Cloudflare. If there’s a valid certificate, then the origin can let the request through and if there’s an invalid certificate or no certificate then the origin can choose to drop the request. However, Authenticated Origin Pull has its limitations and isn’t ideal for some use-cases.
The first limitation is that an Authenticated Origin Pull certificate is tied to a publicly hosted hostname or domain. Some services that are built on Workers don’t necessarily need to be exposed to the public Internet. Therefore, tying it to a domain doesn’t really make sense.
The next limitation is that if you have multiple Workers services that are each writing to the same database, you may want to be able to distinguish them. What if at some point, you need to take the “write” power away from the Worker? Or, what if only Workers A and B are allowed to make writes but Worker C should only make “read” requests?
Today, if you use Authenticated Origin Pulls with Cloudflare’s client certificate then all requests will be accepted as valid. This is because for all outbound requests, we attach the same client certificate. So even though you’re restricting your traffic to “Cloudflare-Only”, there’s no Worker-level granularity.
Now, there’s another solution that you can use. You can make use of Access and set up Token Authentication by using a pre-shared key and configuring your Worker to allow or deny access based on the pre-shared key, presented in the header. While this does allow you to lock down authentication on a per-Worker or per-service basis, the feedback that we’ve gotten from our internal teams who have implemented this is that it’s 1) cumbersome to manage and 2) requires the two service to speak over HTTP, and 3) doesn’t expose the client’s identity. And so, with these limitations in mind, we’re excited to bring mutual TLS authentication to Workers — an easy, scalable way to manage authentication and identity for anyone building on Workers.
Coming soon: Mutual TLS for Workers
We’re excited to announce that in the next few months, we’re going to be bringing mutual TLS support to Workers. Customers will be able to upload client certificates to Cloudflare and attach them in the fetch() requests within a Worker. That way, you can have per-Worker or even per-request level of granularity when it comes to authentication and identification.
When sending out the subrequest, Cloudflare will present the client certificate and the receiving server will be able to check:
1) Is this client presenting a valid certificate? 2) Within Cloudflare, what service or Worker is this request coming from?
This is one of our most highly requested features, both from customers and from internal teams, and we’re excited to launch it and make it a no-brainer for any developer to use Cloudflare as their platform for anything they want to build!
We’re excited to have Xata building their serverless functions product – Xata Workers – on top of Workers for Platforms. Xata Workers act as middleware to simplify database access and allow their developers to deploy functions that sit in front of their databases. Workers for Platforms opens up a whole suite of use cases for Xata developers all while providing the security, scalability and performance of Cloudflare Workers.
Now, handing it over to Alexis, a Senior Software Engineer at Xata to tell us more.
Introduction
In the last few years, there’s been a rise of Jamstack, and new ways of thinking about the cloud that some people call serverless or edge computing. Instead of maintaining dedicated servers to run a single service, these architectures split applications in smaller services or functions.
By simplifying the state and context of our applications, we can benefit from external providers deploying these functions in dozens of servers across the globe. This architecture benefits the developer and user experience alike. Developers don’t have to manage servers, and users don’t have to experience latency. Your application simply scales, even if you receive hundreds of thousands of unexpected visitors.
When it comes to databases though, we still struggle with the complexity of orchestrating replication, failover and high availability. Traditional databases are difficult to scale horizontally and usually require a lot of infrastructure maintenance or learning complex database optimization concepts.
At Xata we are building a modern data platform designed for scalable applications. It allows you to focus on your application logic, instead of having to worry about how the data is stored.
Making databases accessible to everyone
We started Xata with the mission of helping developers build their applications and forget about maintaining the underlying infrastructure.
With that mission in mind, we asked ourselves: how can we make databases accessible to everyone? How can we provide a delightful experience for a frontend engineer or designer using a database?
To begin with, we built an appealing web dashboard, that any developer — no matter their experience — can be comfortable using to work with their data.
Whether they’re defining or refining their schema, viewing or adding records, fine-tuning search results with query boosters, or getting code snippets to speed up development with our SDK. We believe that only the best user experience can provide the best development experience.
We identified a major challenge amongst our user base early on. Many front-end developers want to access their database from client-side code.
Allowing access to a database from client-side code comes with several security risks if not done properly. For example, someone could inspect the code, find the credentials, and if they weren’t scoped to a single operation, potentially query or modify other parts of the database. Unfortunately, this is a common reason for data leaks and security breaches.
It was a hard problem to solve, and after plenty of brainstorming, we agreed on two potential ways forward: implementing row-level access rules or writing API routes that talked to the database from server code.
Row-level access rules are a good way to solve this, but they would have required us to define our own opinionated language. For our users, it would have been hard to migrate away when they outgrow this solution. Instead, we preferred to focus on making serverless functions easier for our users.
Typically, serverless functions require you to either choose a full stack framework or manually write, compile, deploy and use them. This generally adds a lot of cognitive overhead even to choose the right solution. We wanted to simplify accessing the database from the frontend without sacrificing flexibility for developers. This is why we decided to build Xata Workers.
Xata Workers
A Xata Worker is a function that a developer can write in JavaScript or TypeScript as client-side code. Rather than being executed client-side, it will actually be executed on Cloudflare’s global network.
You can think of a Xata Worker as a getServerSideProps function in Next.js or a loader function in Remix. You write your server logic in a function and our tooling takes care of deploying and running it server-side for you (yes, it’s that easy).
The main difference with other alternatives is that Xata Workers are, by design, agnostic to a framework or hosting provider. You can use them to build any kind of application or website, and even upload it as static HTML in a service like GitHub Pages or S3. You don’t need a full stack web framework to use Xata Workers.
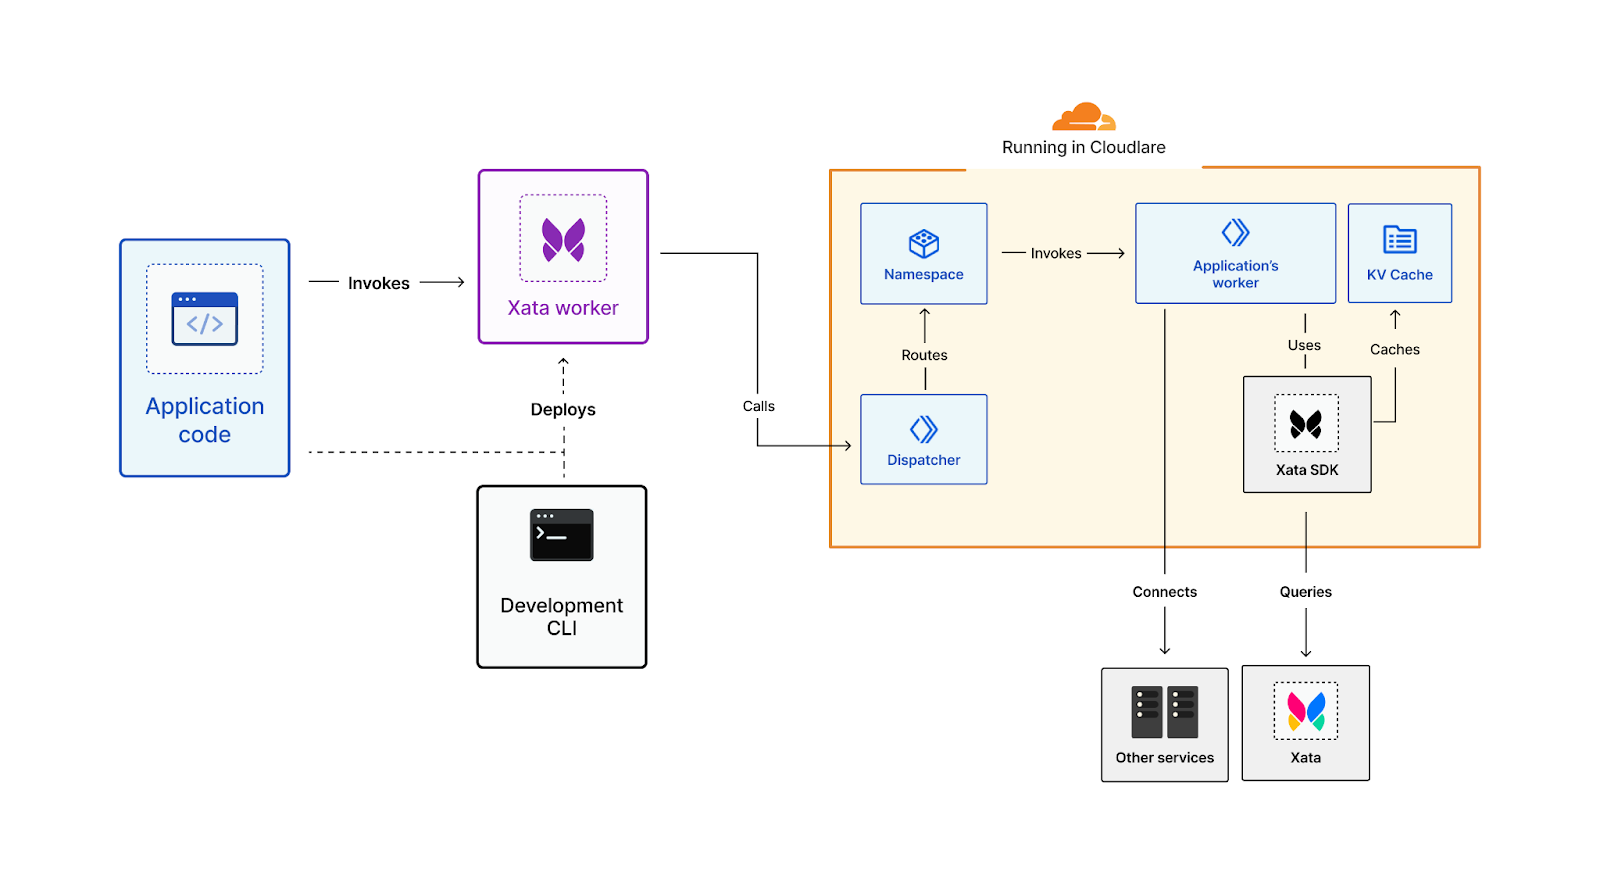
With our command line tool, we handle the build and deployment process. When the function is invoked, the Xata Worker actually makes a request to a serverless function over the network.
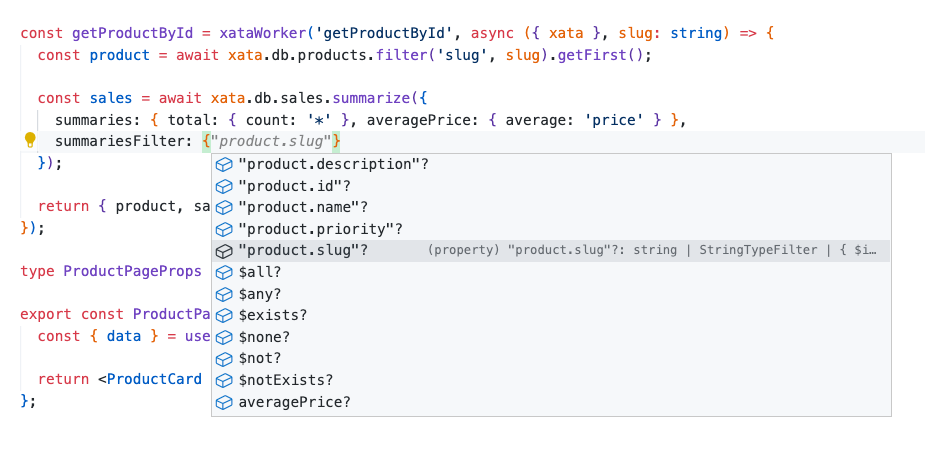
In the code snippet above, you can see a React component that connects to an e-commerce database with products on sale. Inside the UI component, with a popular client-side data fetching library, data is retrieved from the serverless function and for each product it renders another component in a grid.
As you can see a Xata Worker is a function that wraps any user-defined code and receives an instance of our SDK as a parameter. This instance has access to the database and, given that the code doesn’t run on the browser anymore, your secrets are not exposed for malicious usage.
When using a Xata Worker in TypeScript, our command line tool also generates custom types based on your schema. These types offer type-safety for your queries or mutations, and improve your developer experience by adding extra intellisense to your IDE.
A Xata Worker, like any other function, can receive additional parameters that pass application state, context or user tokens. The code you write in the function can either return an object that will be serialized over the network with a superset of JSON to support dates and other non-primitive data types, or a full response with a custom status code and headers.
Developers can write all their logic, including their own authentication and authorization. Unlike complex row level access control rules, you can easily express your logic without constraints and even unit test it with the rest of your code.
How we use Cloudflare
We are happy to join the Supercloud movement, Cloudflare has an excellent track record, and we are using Cloudflare Workers for Platforms to host our serverless functions. By using the Workers isolated execution contexts we reduce security risks of running untrusted code on our own while being close to our users, resulting in super low latency.
All of it, without having to deploy extra infrastructure to handle our user’s application load or ask them to configure how the serverless functions should be deployed. It really feels like magic! Now, let’s dive into the internals of how we use Cloudflare to run our Xata Workers.
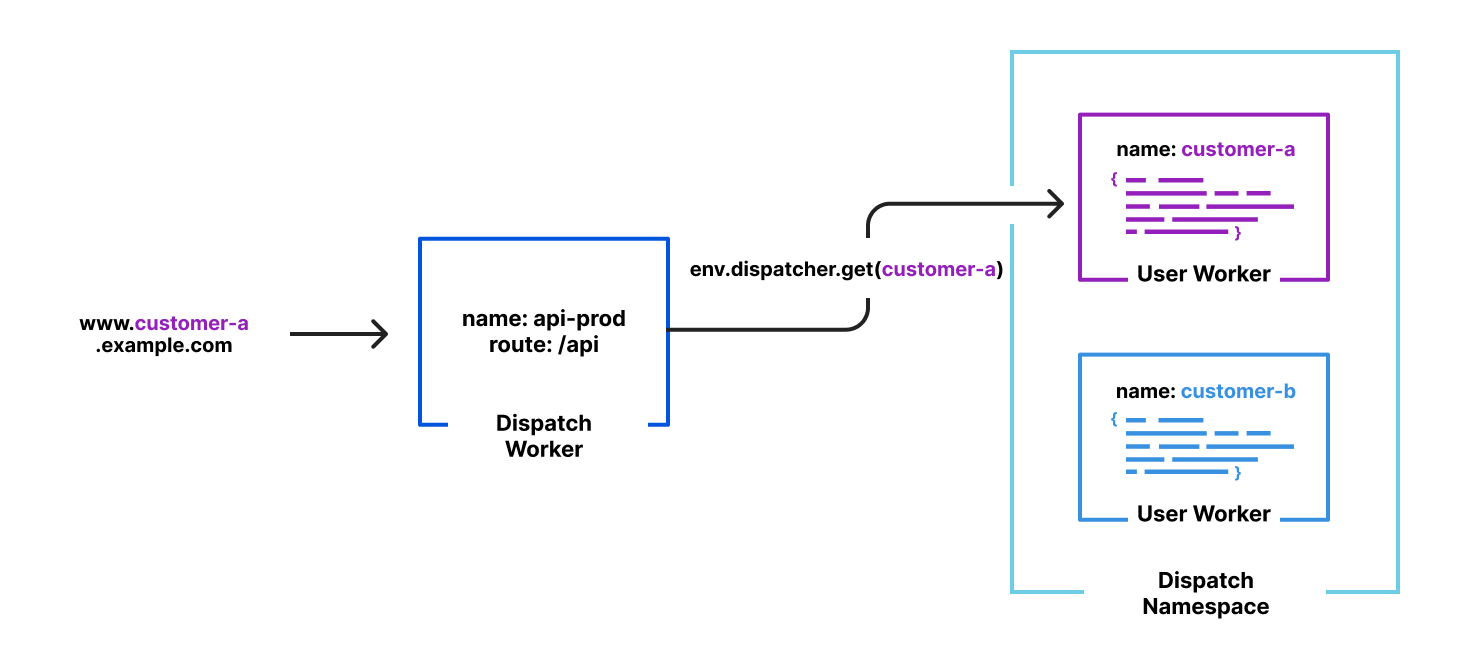
For every workspace in Xata we create a Worker Namespace, a Workers for Platform concept to organize Workers and restrict the routing between them. We used Namespaces to group and encapsulate the different functions coming from all the databases built by a client or team.
When a user deploys a Xata Worker, we create a new Worker Script, and we upload the compiled code to its Namespace. Each script has a unique name with a compilation identifier so that the user can have multiple versions of the same function running at the same time.
During the compilation, we inject the database connection details and the database name. This way, the function can connect to the database without leaking secrets and restricting the scope of access to the database, all of it transparently for the developer.
When the client-side application runs a Xata Worker, it calls a Dispatcher function that processes the request and calls the correct Worker Script. The dispatcher function is also responsible for configuring the CORS headers and the log drain that can be used by the developer to debug their functions.
By using Cloudflare, we are also able to benefit from other products in the Workers ecosystem. For example, we can provide an easy way to cache the results of a query in Cloudflare’s global network. That way, we can serve the results for read-only queries directly from locations closer to the end users, without having to call the database again and again for every Worker invocation. For the developer, it’s only a matter of adding a “cache” parameter to their query with the number of milliseconds they want to cache the results in a KV Namespace.
In development mode, we provide a command to run the functions locally and test them before deploying them to production. This enables rapid development workflows with real-time filesystem change monitoring and hot reloading of the workers code. Internally, we use the latest version of miniflare to emulate the Cloudflare Workers runtime, mimicking the real production environment.
Conclusion
Xata is now out of beta and available for everyone. We offer a generous free tier that allows you to build and deploy your applications and only pay to scale them when you actually need it.
You can sign up for free, create a database in seconds and enjoy features such as branching with zero downtime migrations, search and analytics, transactions, and many others. Check out our website to learn more!
Xata Workers are currently in private beta. If you are interested in trying them out, you can sign up for the waitlist and talk us through your use case. We are looking for developers that are willing to provide feedback and shape this new feature for our serverless data platform.
We are very proud of our collaboration with Cloudflare for this new feature. Processing data closer to where it’s being requested is the future of computing and we are excited to be part of this movement. We look forward to seeing what you build with Xata Workers.
If you’ve ever created a website that shows any kind of analytics, you’ve probably also thought about adding a “Save Image” or “Save as PDF” button to store and share results. This isn’t as easy as it seems (I can attest to this firsthand) and it’s not long before you go down a rabbit hole of trying 10 different libraries, hoping one will work.
This is why we’re excited to announce a private beta of the Workers Browser Rendering API, improving the browser automation experience for developers. With browser automation, you can programmatically do anything that a user can do when interacting with a browser.
The Workers Browser Rendering API, or just Rendering API for short, is our out-of-the-box solution for simplifying developer workflows, including capturing images or screenshots, by running browser automation in Workers.
Browser automation, everywhere
As with many of the best Cloudflare products, Rendering API was born out of an internal need. Many of our teams were setting up or wanted to set up their own tools to perform what sounds like an incredibly simple task: taking automated screenshots.
When gathering use cases, we realized that much of what our internal teams wanted would also be useful for our customers. Some notable ones are:
Taking screenshots for social sharing thumbnails or preview images
Emailed daily screenshots of dashboards (requested specifically by our SVP of Engineering)
Reporting bugs on websites and sending them directly to frontend teams
Not to mention use cases for other browser automation functions like:
Testing UI/UX Flows End-to-end (E2E) testing is used to minimic user behaviour and can identify bugs that unit tests or integration tests have missed. And let’s be honest – no developer wants to manually check the user flow each time they make changes to their application. E2E tests can be especially useful to verify logic on your customer’s critical path like account creation, authentication or checkout.
Performance Tests Application performance metrics, such as page load time, directly impact your user’s experience and your SEO rankings. To avoid performance regressions, you want to test impact on latency in conditions that are as close as possible to your production environment before you merge. By automating performance testing you can measure if your proposed changes will result in a degraded experience for your uses and make improvements accordingly.
Unlocking a new building block
One of the most common browser automation frameworks is Puppeteer. It’s common to run Puppeteer in a containerization tool like Docker or in a serverless environment. Taking automated screenshots should be as easy as writing some code, hitting deploy and having it run when a particular event is triggered or on a regular schedule.
It should be, but it’s not.
Even on a serverless solution like AWS Lambda, running Puppeteer means packaging it, making sure dependencies are covered, uploading packages to S3 and deploying using Layers. Whether using Docker or something like Lambda, it’s clear that this is not easy to set up.
One of the pillars of Cloudflare’s development platform is to provide our developers with tools that are incredibly simple, yet powerful to build on. Rendering API is our out-of-the-box solution for running Puppeteer in Workers.
Screenshotting made simple
To start, the Rendering API will have support for navigating to a webpage and taking a screenshot, with more functions to follow. To use it, all you need to do is add our new browser binding to your project’s wrangler.toml file
wrangler.toml
bindings = [
 { name = "my_browser” type = "browser" }
]
From there, taking a screenshot and saving it to R2 is as simple as:
Down the line, we have plans to add full Puppeteer support, including functions like page.type, page.click, page.evaluate!
What’s happening under the hood?
Remote browser isolation technology is an integral part of our Zero Trust product offering. Remote browser isolation lets users interact with a web browser that instead of running on the client’s device, runs in a remote environment. The Rendering API repurposes this under the hood!
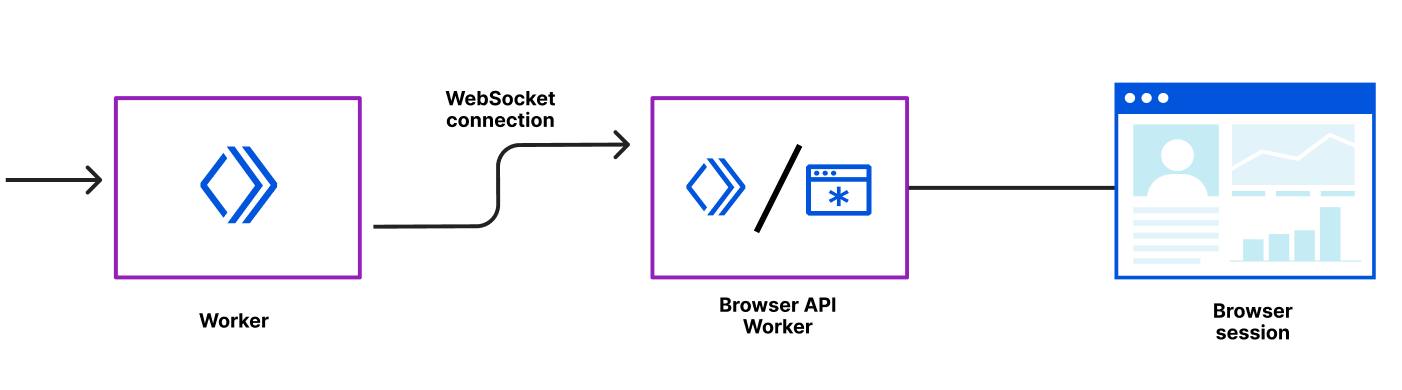
We’ve wrapped the Puppeteer library so that it can be run directly from your own Worker. You can think of your Worker as the client. Each of Cloudflare’s data centers has a pool of warm browsers ready to go and when a Worker requests a browser, the browser is instantly returned and is connected to via a WebSocket. Once the WebSocket connection is established, our internal browser API Worker handles all communication to the browser session via the Chrome Devtools Protocol.
To ensure the security of your Worker, individual remote browsers are run as disposable instances – one instance per request, and never shared. They are secured using gVisor to protect against kernel level exploits. On top of that, the browser is running sandboxed processes with the lowest privilege level using a Linux seccomp profile.
The Rendering API should be used when you’re building and testing your applications. To prevent abuse, Cloudflare Bot Management has baked in signals to indicate that a request is coming from a Worker running Puppeteer. As a Cloudflare Bot Management customer, this will automatically be added to your blocklist, with the option to explicitly opt in and allow it.
How can you get started?
We’re introducing the Workers Browser Rendering API in closed beta. If you’re interested, please tell us a bit about your use case and join the waitlist. We would love to hear what else you want to build using the Workers Browser Rendering API, let us know in the Workers channel on the Cloudflare Developers Discord!
There are many ways to store data in your applications. For example, in Cloudflare Workers applications, we have Workers KV for key-value storage and Durable Objects for real-time, coordinated storage without compromising on consistency. Outside the Cloudflare ecosystem, you can also plug in other tools like NoSQL and graph databases.
But sometimes, you want SQL. Indexes allow us to retrieve data quickly. Joins enable us to describe complex relationships between different tables. SQL declaratively describes how our application’s data is validated, created, and performantly queried.
D1 was released today in open alpha, and to celebrate, I want to share my experience building apps with D1: specifically, how to get started, and why I’m excited about D1 joining the long list of tools you can use to build apps on Cloudflare.
D1 is remarkable because it’s an instant value-add to applications without needing new tools or stepping out of the Cloudflare ecosystem. Using wrangler, we can do local development on our Workers applications, and with the addition of D1 in wrangler, we can now develop proper stateful applications locally as well. Then, when it’s time to deploy the application, wrangler allows us to both access and execute commands to your D1 database, as well as your API itself.
What we’re building
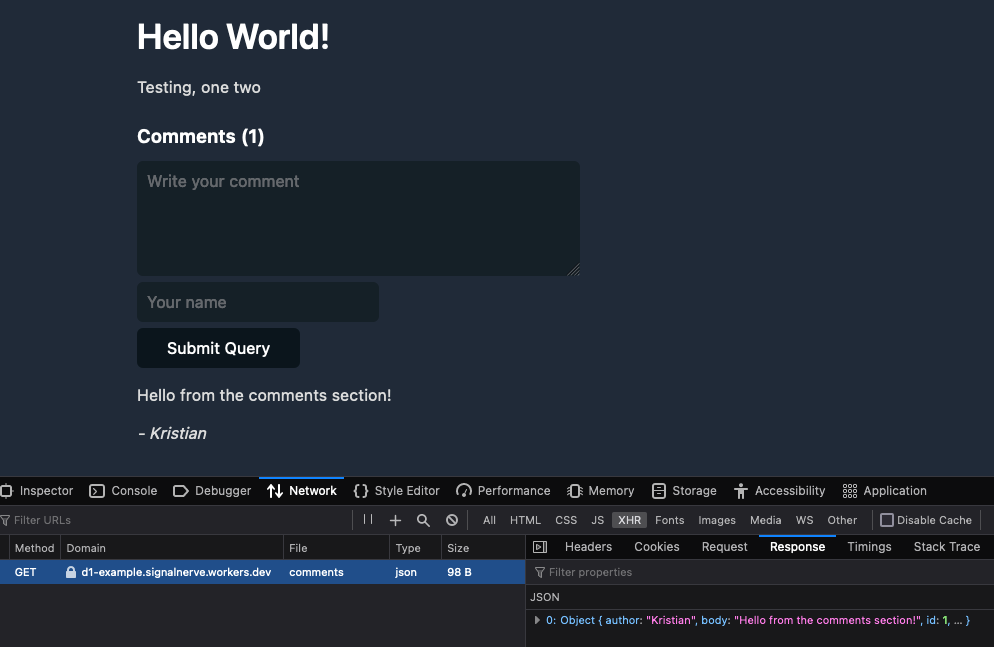
In this blog post, I’ll show you how to use D1 to add comments to a static blog site. To do this, we’ll construct a new D1 database and build a simple JSON API that allows the creation and retrieval of comments.
As I mentioned, separating D1 from the app itself – an API and database that remains separate from the static site – allows us to abstract the static and dynamic pieces of our website from each other. It also makes it easier to deploy our application: we will deploy the frontend to Cloudflare Pages, and the D1-powered API to Cloudflare Workers.
Building a new application
First, we’ll add a basic API in Workers. Create a new directory and in it a new wrangler project inside it:
$ mkdir d1-example && d1-example
$ wrangler init
In this example, we’ll use Hono, an Express.js-style framework, to rapidly build our API. To use Hono in this project, install it using NPM:
$ npm install hono
Then, in src/index.ts, we’ll initialize a new Hono app, and define a few endpoints – GET /API/posts/:slug/comments, and POST /get/api/:slug/comments.
import { Hono } from 'hono'
import { cors } from 'hono/cors'

const app = new Hono()

app.get('/api/posts/:slug/comments', async c => {
  // do something
})

app.post('/api/posts/:slug/comments', async c => {
  // do something
})

export default app
Now we’ll create a D1 database. In Wrangler 2, there is support for the wrangler d1 subcommand, which allows you to create and query your D1 databases directly from the command line. So, for example, we can create a new database with a single command:
$ wrangler d1 create d1-example
With our created database, we can take the database name ID and associate it with a binding inside of wrangler.toml, wrangler’s configuration file. Bindings allow us to access Cloudflare resources, like D1 databases, KV namespaces, and R2 buckets, using a simple variable name in our code. Below, we’ll create the binding DB and use it to represent our new database:
[[ d1_databases ]]
binding = "DB" # i.e. available in your Worker on env.DB
database_name = "d1-example"
database_id = "4e1c28a9-90e4-41da-8b4b-6cf36e5abb29"
Note that this directive, the [[d1_databases]] field, currently requires a beta version of wrangler. You can install this for your project using the command npm install -D wrangler/beta.
With the database configured in our wrangler.toml, we can start interacting with it from the command line and inside our Workers function.
First, you can issue direct SQL commands using wrangler d1 execute:
$ wrangler d1 execute d1-example --command "SELECT name FROM sqlite_schema WHERE type ='table'"
Executing on d1-example:
┌─────────────────┐
│ name │
├─────────────────┤
│ sqlite_sequence │
└─────────────────┘
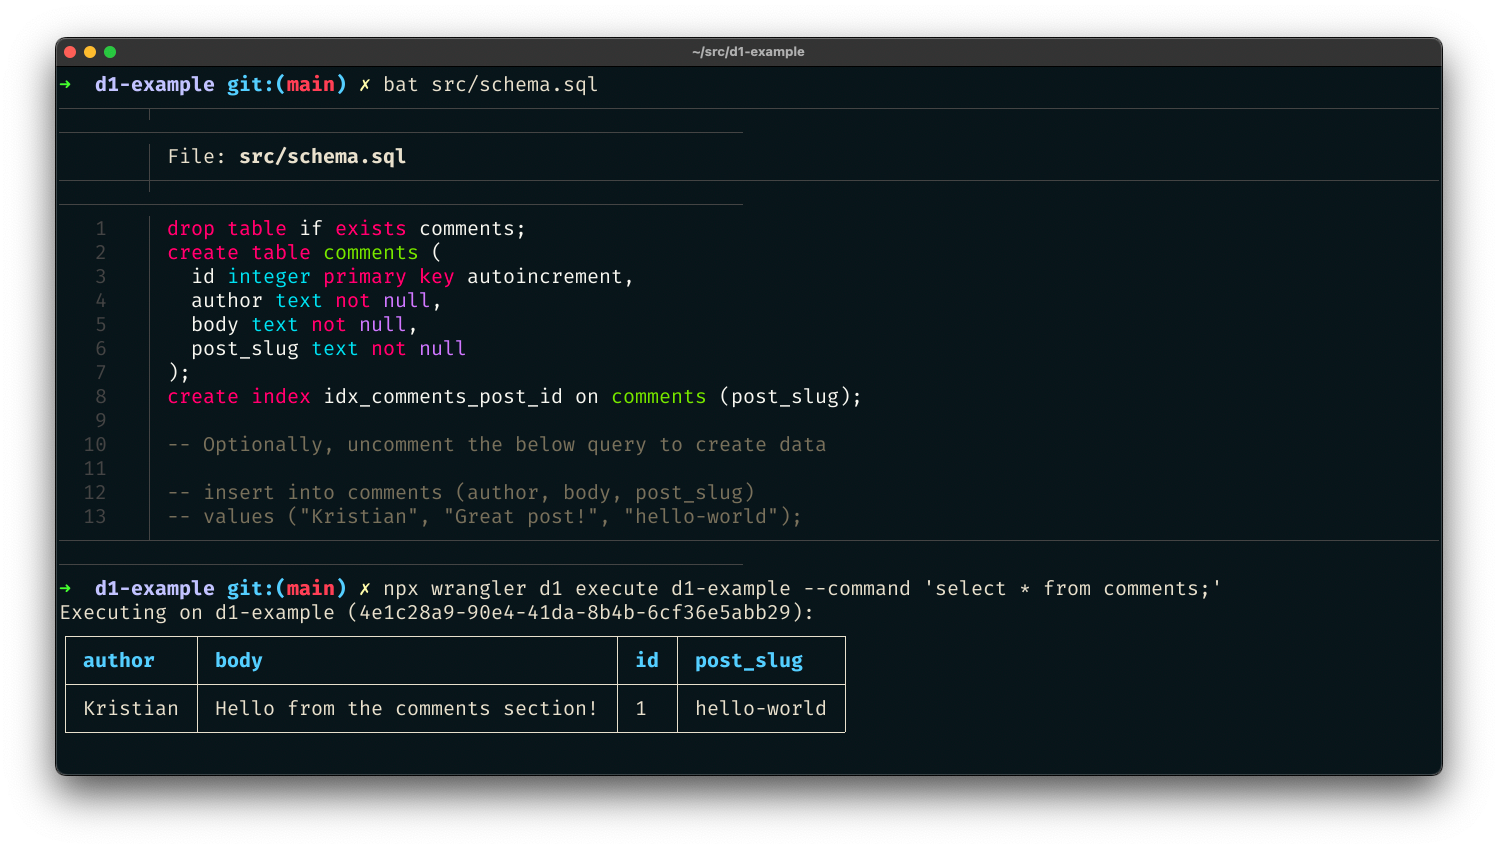
You can also pass a SQL file – perfect for initial data seeding in a single command. Create src/schema.sql, which will create a new comments table for our project:
drop table if exists comments;
create table comments (
  id integer primary key autoincrement,
  author text not null,
  body text not null,
  post_slug text not null
);
create index idx_comments_post_id on comments (post_slug);

-- Optionally, uncomment the below query to create data

-- insert into comments (author, body, post_slug)
-- values ("Kristian", "Great post!", "hello-world");
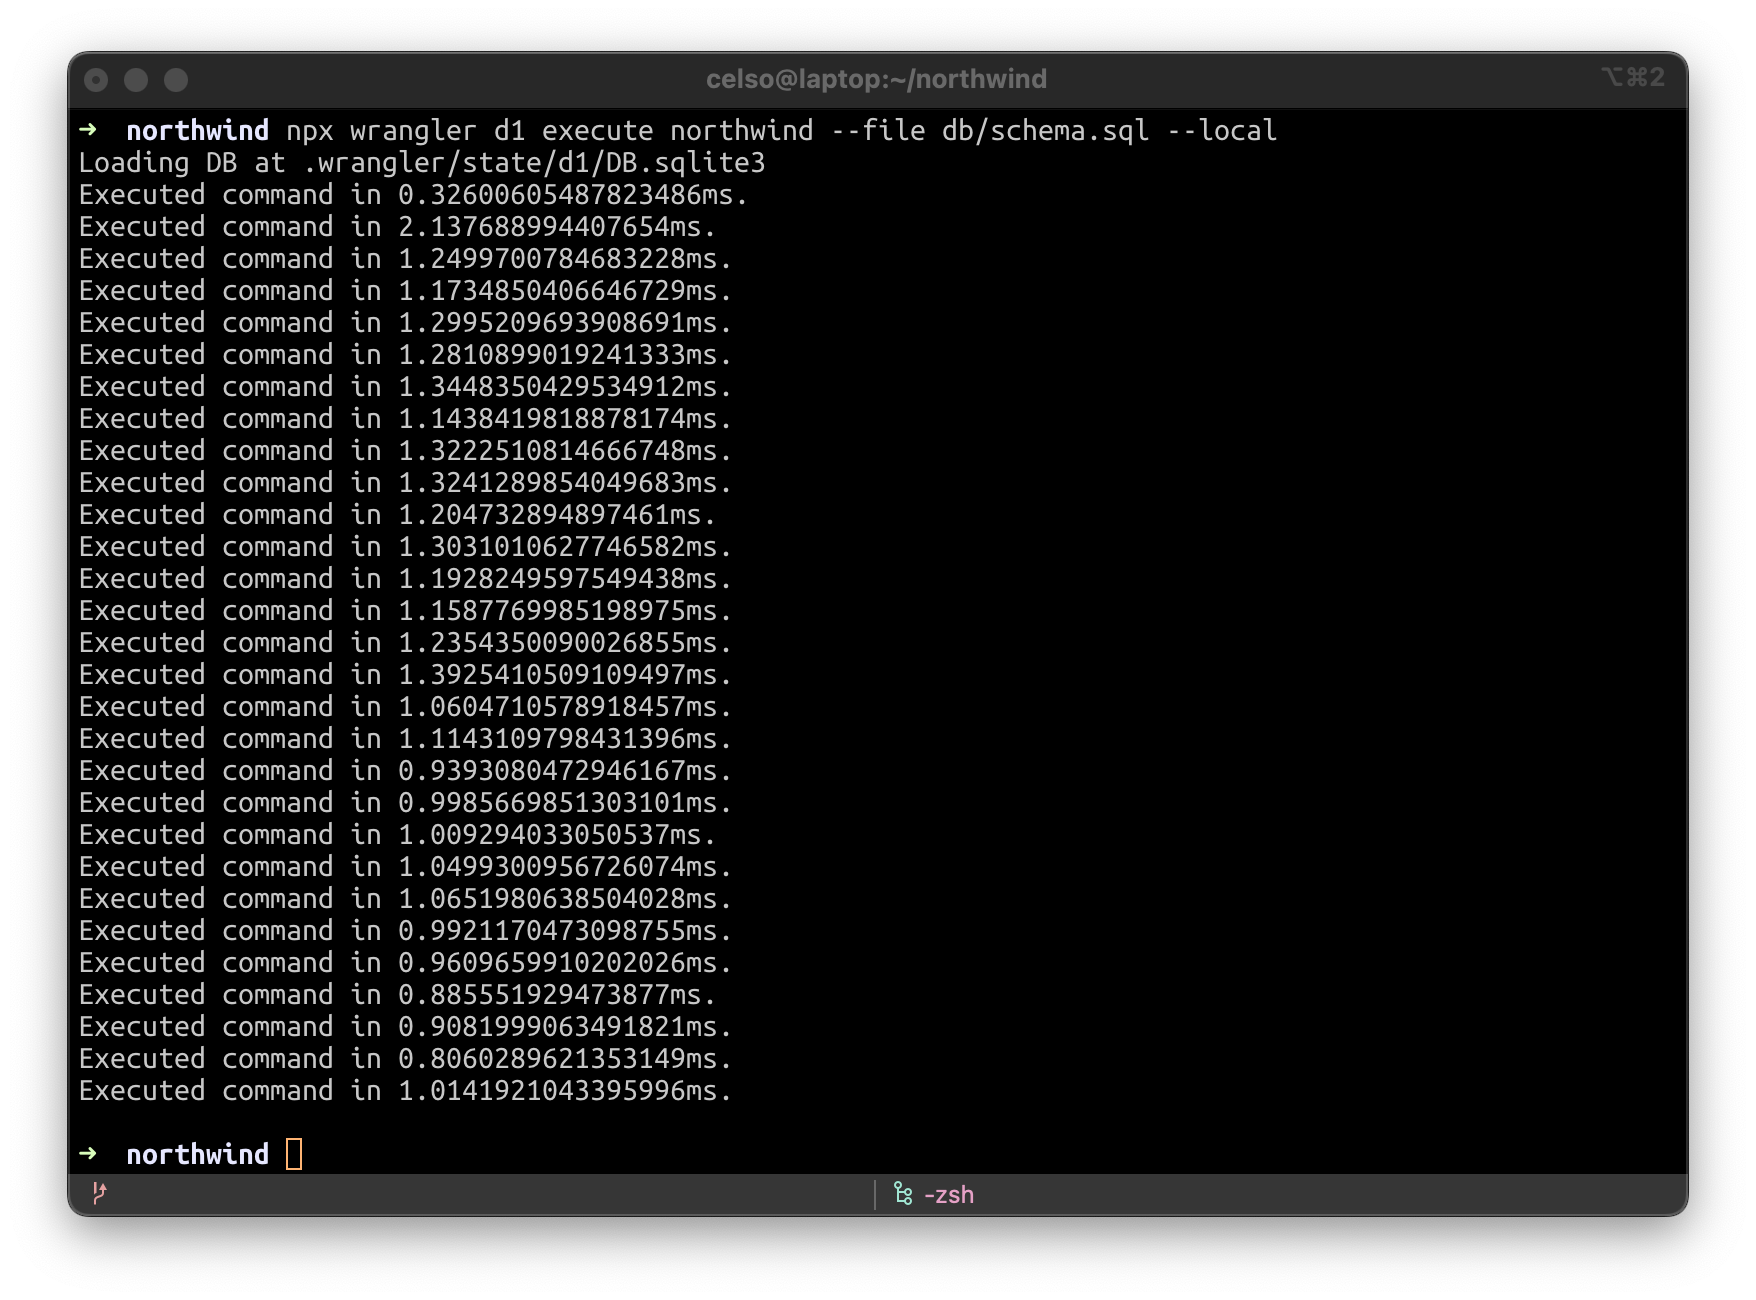
With the file created, execute the schema file against the D1 database by passing it with the flag --file:
We’ve created a SQL database with just a few commands and seeded it with initial data. Now we can add a route to our Workers function to retrieve data from that database. Based on our wrangler.toml config, the D1 database is now accessible via the DB binding. In our code, we can use the binding to prepare SQL statements and execute them, for instance, to retrieve comments:
app.get('/api/posts/:slug/comments', async c => {
  const { slug } = c.req.param()
  const { results } = await c.env.DB.prepare(`
    select * from comments where post_slug = ?
  `).bind(slug).all()
  return c.json(results)
})
In this function, we accept a slug URL query parameter and set up a new SQL statement where we select all comments with a matching post_slug value to our query parameter. We can then return it as a simple JSON response.
So far, we’ve built read-only access to our data. But “inserting” values to SQL is, of course, possible as well. So let’s define another function that allows POST-ing to an endpoint to create a new comment:
app.post('/API/posts/:slug/comments', async c => {
  const { slug } = c.req.param()
  const { author, body } = await c.req.json<Comment>()

  if (!author) return c.text("Missing author value for new comment")
  if (!body) return c.text("Missing body value for new comment")

  const { success } = await c.env.DB.prepare(`
    insert into comments (author, body, post_slug) values (?, ?, ?)
  `).bind(author, body, slug).run()

  if (success) {
    c.status(201)
    return c.text("Created")
  } else {
    c.status(500)
    return c.text("Something went wrong")
  }
})
In this example, we built a comments API for powering a blog. To see the source for this D1-powered comments API, you can visit cloudflare/templates/worker-d1-api.
Conclusion
One of the things most exciting about D1 is the opportunity to augment existing applications or websites with dynamic, relational data. As a former Ruby on Rails developer, one of the things I miss most about that framework in the world of JavaScript and serverless development tools is the ability to rapidly spin up full data-driven applications without needing to be an expert in managing database infrastructure. With D1 and its easy onramp to SQL-based data, we can build true data-driven applications without compromising on performance or developer experience.
This shift corresponds nicely with the advent of static sites in the last few years, using tools like Hugo or Gatsby. A blog built with a static site generator like Hugo is incredibly performant – it will build in seconds with small asset sizes.
But by trading a tool like WordPress for a static site generator, you lose the opportunity to add dynamic information to your site. Many developers have patched over this problem by adding more complexity to their build processes: fetching and retrieving data and generating pages using that data as part of the build.
This addition of complexity in the build process attempts to fix the lack of dynamism in applications, but it still isn’t genuinely dynamic. Instead of being able to retrieve and display new data as it’s created, the application rebuilds and redeploys whenever data changes so that it appears to be a live, dynamic representation of data. Your application can remain static, and the dynamic data will live geographically close to the users of your site, accessible via a queryable and expressive API.
One of the things we prioritize at Cloudflare is enabling developers to build their applications on our developer platform with ease. We’re excited to share a collection of ready-made templates that’ll help you start building your next application on Workers. We want developers to get started as quickly as possible, so that they can focus on building and innovating and avoid spending so much time configuring and setting up their projects.
Cloudflare Workers enables you to build applications with exceptional performance, reliability, and scale. We are excited to share a collection of templates that helps you get started quickly and give you an idea of what is possible to build on our developer platform.
We have made available a set of starter templates highlighting different use cases of Workers. We understand that you have different ideas you will love to build on top of Workers and you may have questions or wonder if it is possible. These sets of templates go beyond the convention ‘Hello, World’ starter. They’ll help shape your idea of what kind of applications you can build with Workers as well as other products in the Cloudflare Developer Ecosystem.
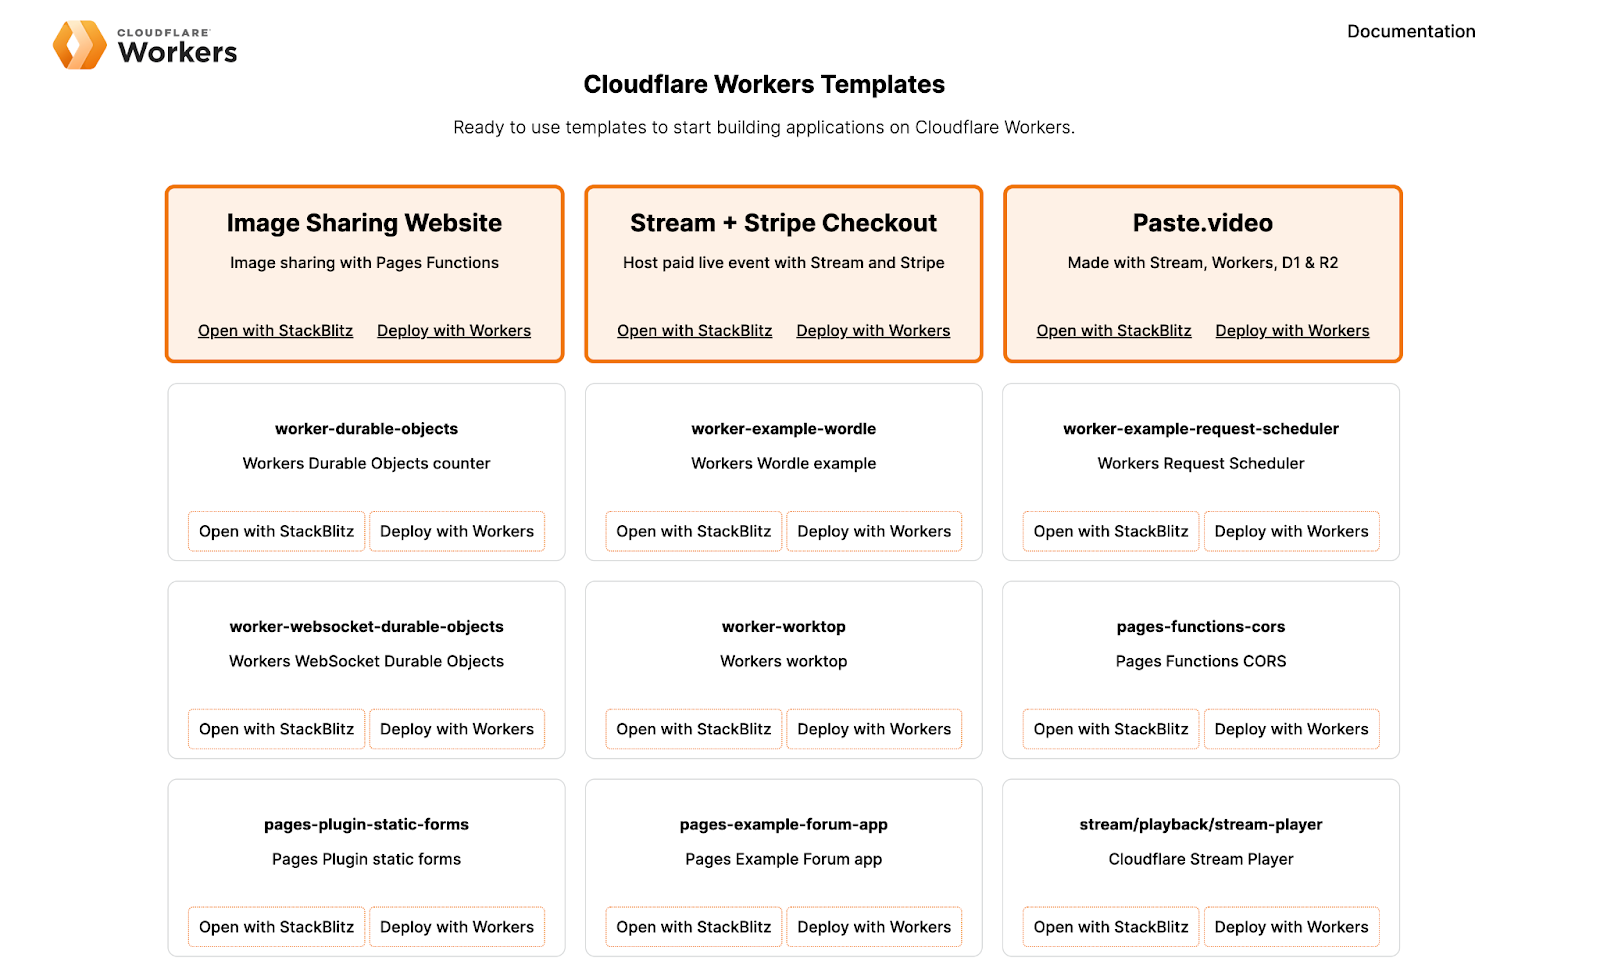
We are excited to introduce a new collection of starter templates workers.new/templates. This shortcut will serve you a collection of templates that you can immediately start using to build your next application.
Cloudflare Workers Template Collection
How to use Cloudflare Workers templates
We created this collection of templates to support you in getting started with Workers. Some examples listed showcase a use-case with a combination of multiple Cloudflare developer platform products to build applications similar to ones you might use every day. We know that Workers are being used today for different use-cases, we want to showcase some of them to you.
One example to highlight is a template that lets you accept payment for video content. It is powered by Pages Functions, Cloudflare Stream and Stripe Checkout. This app shows how you can use Cloudflare Workers with external payment and authentication systems to create a logged-in experience, without ever having to manage a database or persist any state yourself.
Once a user has paid, Stripe Checkout redirects to a URL that verifies a token from Stripe, and generates a signed URL using Cloudflare Stream to view the video. This signed URL is only valid for a specified amount of time, and access can be restricted by country or IP address.
To use the template, you need to either click the deploy with Workers button or open the template with Stackblitz.
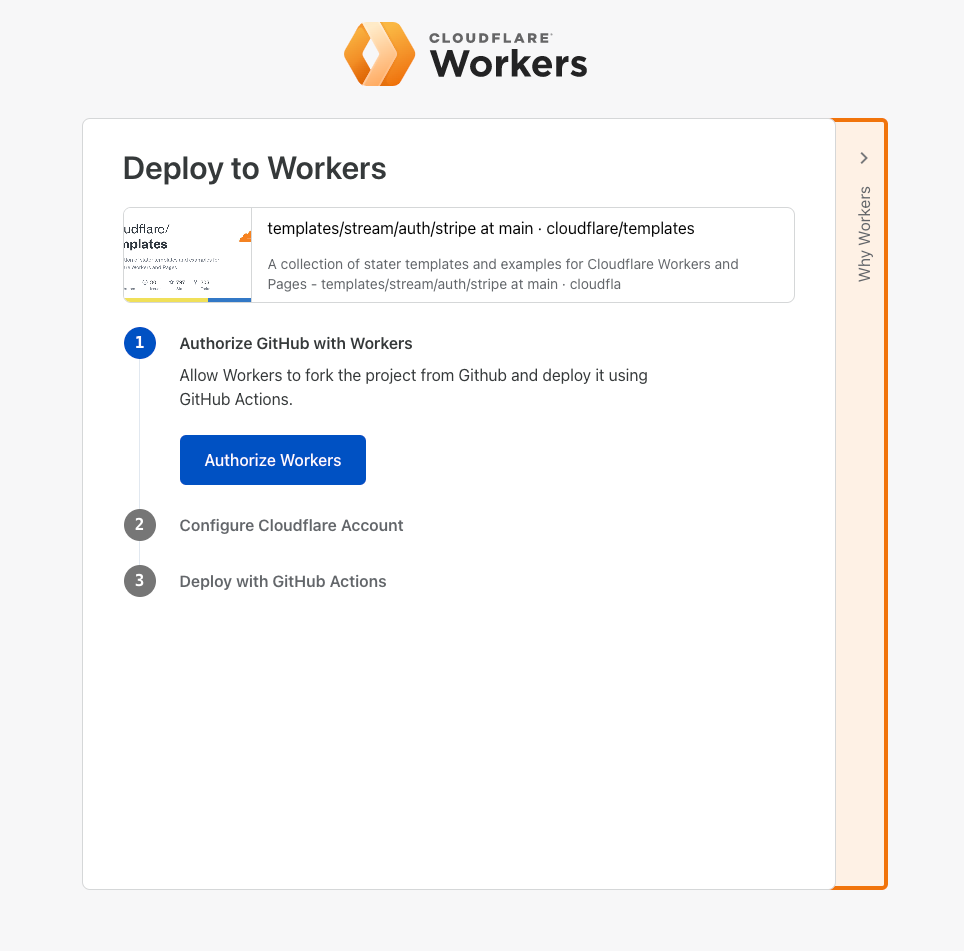
The Deploy with Workers button will redirect you to a page where you can authorize GitHub to deploy a fork of the repository using GitHub actions while opening with StackBlitz creates a new fork of the template for you to start working with.
Deploy to Workers Demo
These templates also comes bundled with additional features I would like to share with you:
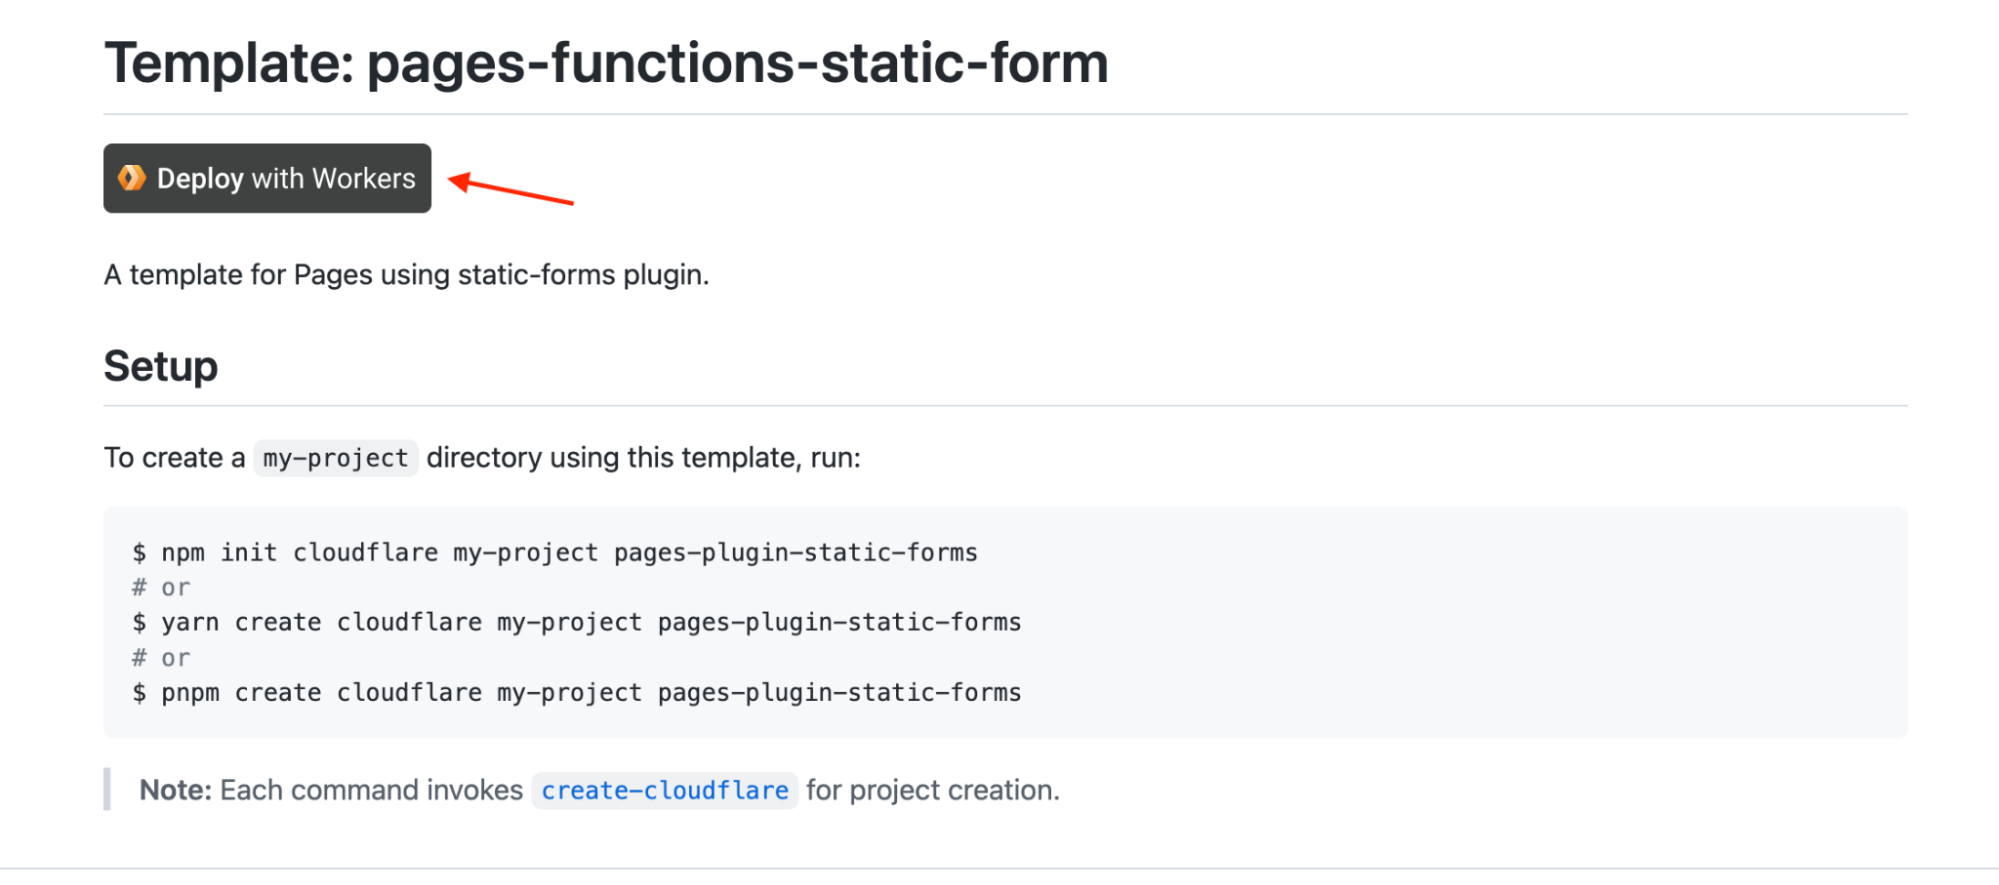
We added a deploy button to all templates listed in the templates repository and the collection website, so you can quickly get up to speed with your code. The deploy with Workers button lets you deploy your code in under five minutes, it uses a GitHub action powered with Cloudflare Workers to do this.
GitHub Repository with Deploy to Workers Button
Support for Test Driven Development
As developers, we need to write tests for our code to ensure we’re shipping quality production grade software and also ensure that our code is bug-free. We support writing tests in Workers using the Wrangler unstable_dev API to write integration and end-to-end tests. We want to enable not just the developer experience but also nudge developers to follow best practices and prioritize TDD in development. We configured a number of templates to support integration tests against a local server, this will serve as a template to help you set up tests in your projects.
Here’s an example using Wrangler’s unstable_dev API and Vitest test framework to test the code written in an example ‘Hello worker’ starter template:
We announced StackBlitz’s partnership with Cloudflare Workers during Platform Week early this year. We believe a developer’s experience should be of utmost priority because we want them to build with ease on our developer platform.
StackBlitz is an online development platform for building web applications. It is powered by WebContainers, the first WebAssembly-based operating system which boots Node.js environments in milliseconds, securely within your browser tab.
We made it even easier to get started with Workers with an integrated Open with StackBlitz button for each starter template, making it easier to create a fork of a template and the great thing is you only need a web browser to build your application.
Everything we’ve highlighted in this post, all leads to one thing – How can we create a better experience for developers getting started with Workers. We introduce these ready-made templates to make you more efficient, bring you a wholesome developer experience and help improve your time to deployment. We want you to spend less time getting started with building on the Workers developer platform, so what are you waiting for?
Next Steps
You can start building your own Worker today using the available templates provided in the templates collection to help you get started. If you would like to contribute your own templates to the collection, be sure to send in a pull request we’re more than happy to review and add to the growing collection. Share what you have built with us in the #builtwith channel on our Discord community. Make sure to follow us on Twitter or join our Discord Developers Community server.
Our customers rely on their Cloudflare logs to troubleshoot problems and debug issues. One of the biggest challenges with logs is the cost of managing them, so earlier this year, we launched the ability to store and retrieve Cloudflare logs using R2.
In this post, I’ll explain how we built the R2 Log Retrieval API using Cloudflare Workers with a focus on Durable Objects and the Streams API. Using these, allows a customer to index and query millions of their Cloudflare logs stored in batches on R2.
Before we dive into the internals you might be wondering why one doesn’t just use a traditional database to index these logs? After all, databases are a well proven technology. Well, the reason is that individual developers or companies, both large and small, often don’t have the resources necessary to maintain such a database and the surrounding infrastructure to create this kind of setup.
Our approach instead relies on Durable Objects to maintain indexes of the data stored in R2, removing the complexity of managing and maintaining your own database. It was also super easy to add Durable Objects to our existing Workers code with just a few lines of config and some code. And R2 is very economical.
Indexing
Indexing data is often used to reduce the lookup time for a query by first pre-processing the data and computing an index – usually a file (or set of files) that have a known structure which can be used to perform lookups on the underlying data. This approach makes lookups quick as indexes typically contain the answer for a given query, or at the very least, tells you how to find it. For this project we are going to index records by the unique identifier called a RayID which our customers use to identify an HTTP request in their logs, but this solution can be modified to index any many other types of data.
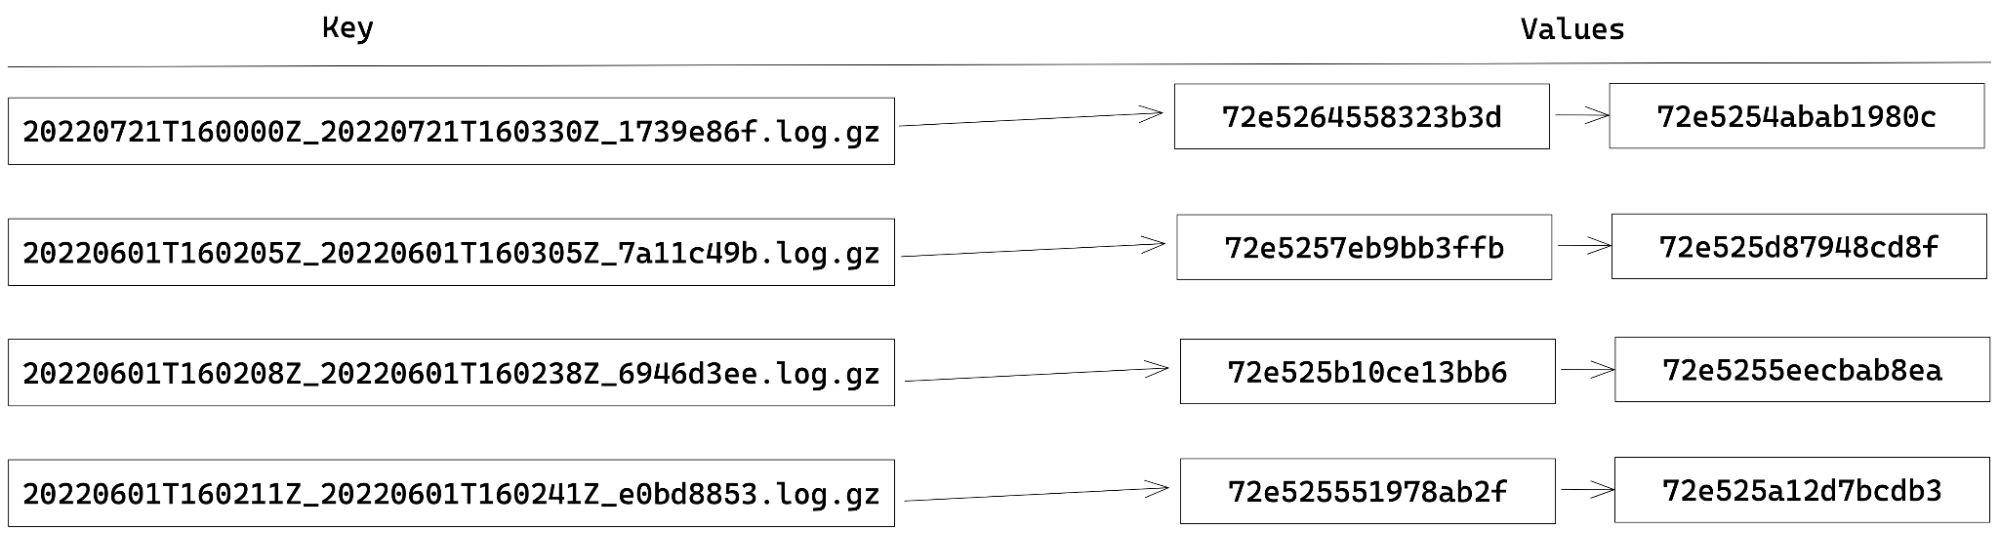
When indexing RayIDs for logs stored in R2, we choose an index structure that is fairly straightforward and is commonly known as a forward-index. This type of index consists of a key-value mapping between a document’s name and a list of words contained in that document. The terms “document” and “words” are meant to be generic, and you get to define what a document and a word is.
In our case, a document is a batch of logs stored in R2 and the words are RayIDs contained within that document. For example, our index currently looks like this:
Building an index using Durable Objects and the Streams API
In order to maintain the state of our index, we chose to use Durable Objects. Each Durable Object has its own transactional key-value storage. Therefore, to store our index, we assign each key to be the document (batch) name and the value being a JSON-array of RayIDs within that document. When extracting the RayIDs for a given batch, updating the index becomes as simple as storage.put(batchName, rayIds). Likewise, getting all the RayIDs for a document is just a call to storage.get(batchName).
When performing indexing, since the batches are stored using compression and often with a 30-100x compression ratio, reading an entire batch into memory can lead to out-of-memory (OOM) errors in our Worker. To get around this, we use the Streams API to avoid the OOM errors by processing the data in smaller chunks. There are two types of streams available: byte-oriented and value-oriented. Byte-oriented streams operate at the byte-level for things such as compressing and decompressing data, while the value-orientated streams work on first class values in JavaScript. Numbers, strings, undefined, null, objects, you name it. If it’s a valid JavaScript value, you can process it using a value-oriented stream. The Streams API also allows us to define our own JavaScript transformations for both byte- and value-oriented streams.
So, when our API receives a request to index a batch, our Worker streams the contents from R2 into a pipeline of TransformationStreams to decompress the data, decode the bytes into strings, split the data into records based on the newlines, and finally collect all the RayIDs. Once we’ve collected all the RayIDs, the data is then persisted in the index by making calls to the Durable Object, which in turn calls the aforementioned storage.put method to persist the data to the index. To illustrate what I mean, I include some code detailing the steps described above.
async function index(r2, bucket, key, storage) {
  const obj = await getObject(r2, bucket, key);

  const rawStream = obj.Body as ReadableStream;
  const index: Record<string, string[]> = {};

  const rayIdIndexingStream = new TransformStream({
    transform(chunk: string) {
      for (const match of chunk.matchAll(RAYID_FIELD_REGEX)) {
        const { rayid } = match.groups!;
        if (key in index) {
          index[key].push(rayid);
        } else {
          index[key] = [rayid];
        }
      }
    }
  });

  await collectStream(rawStream.pipeThrough(new DecompressionStream('gzip')).pipeThrough(textDecoderStream()).pipeThrough(readlineStream()).pipeThrough(rayIdIndexingStream));
  storage.put(index);
}
Searching for a RayID
Once a batch has been indexed, and the index is persisted to our Durable Object, we can then query it using a combination of the RayID and a batch name to check the presence of a RayID in that given batch. Assuming that a zone is producing a batch of logs at the rate of one batch per second this means that over 86,400 batches would be produced in a day! Over the course of a week, there would be far too many keys in our index for us to be able to iterate through them all in a timely manner. This is where the encoding of a RayID and the naming of each batch comes into play.
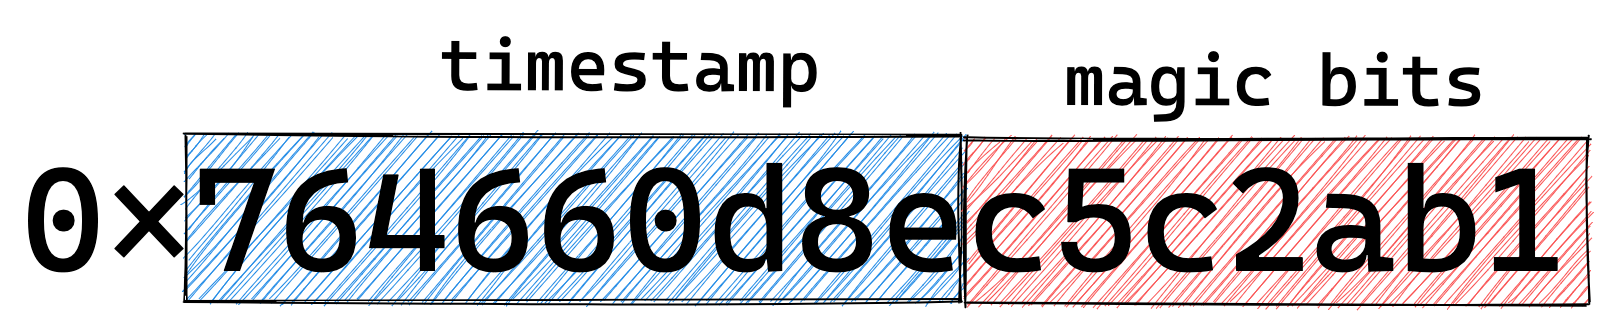
A RayID is currently, and I emphasize currently because this can change and has over time, a 16-byte hex encoded value where the first 36-bits encode a timestamp, and it looks something like: 764660d8ec5c2ab1. Note that the format of the RayID is likely to evolve in the near future, but for now we can use it to optimize retrieval.
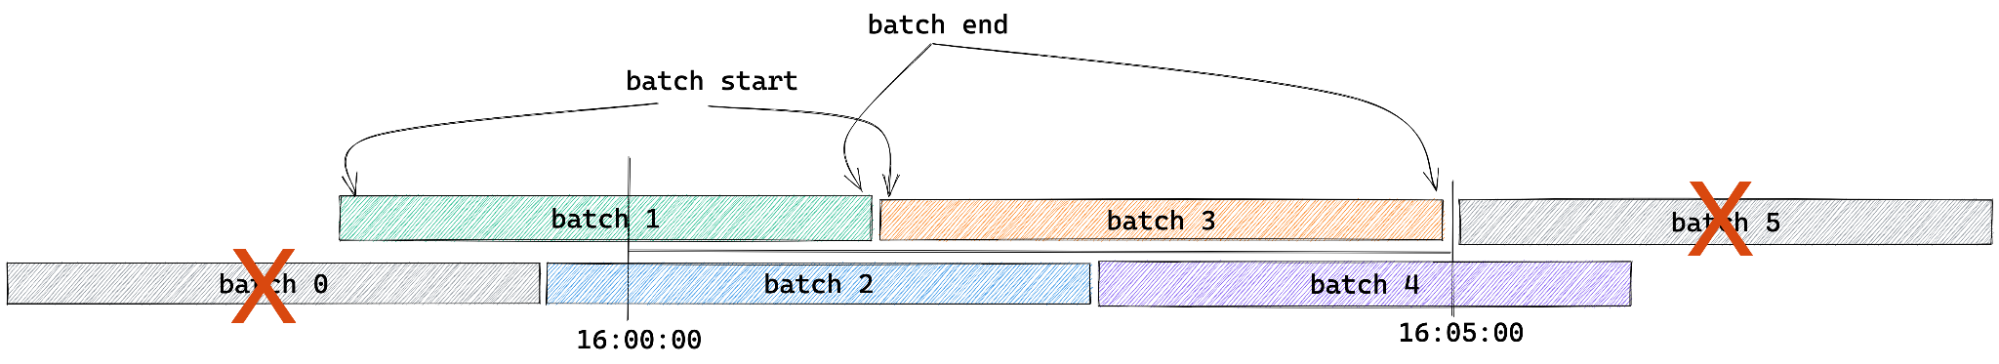
Each batch produced by Logpush also happens to encode the time the batch was started and completed. Last but not least, upon analysis of our logging pipeline we found that 95% of RayIDs can be found in a batch produced within five minutes of the request completing. (Note that the encoded time sets a lower bound of the batch time we need to search).
Encoding of a RayIDEncoding of a batch name
For example: say we have a request that was made on November 3 at 16:00:00 UTC. We only need to check the batches under the prefix 20221103 and those batches that contain the time range of 16:00:00 to 16:05:00 UTC.
By reducing the number of batches to just a small handful of possibilities for a given RayID, we can simply ask our index if any of those batches contains the RayID by iterating through all the batch names (keys).
If the RayID is found in a batch, we then stream the corresponding batch back from R2 using another TransformationStream pipeline to filter out any non-matching records from the final response. If no result was found, we return an error message saying we were unable to find the RayID.
Summary
To recap, we showed how we can use Durable Objects and their underlying storage to create and manage forward-indexes for performing efficient lookup on the RayID for potentially millions of records. All without needing to manage your own database or logging infrastructure or doing a full-scan of the data.
While this is just one possible use case for Durable Objects, we are just getting started. If you haven’t read it before, checkout How we built Instant Logs to see another application of Durable Objects to stream millions of logs in real-time to your Cloudflare Dashboard!
What’s next
We currently offer RayID lookups for the HTTP Requests, Firewall Events, and soon support for Workers Trace Events. This is just the beginning for our Log Retrieval API, and we are already looking to add the ability to index and query on more types of fields such as status codes and host names. We also plan to integrate this into the dashboard so that developers can quickly retrieve the logs they need without needing to craft the necessary API calls by hand.
Last but not least, we want to make our retrieval functionality even more powerful and are looking at adding more complex types of filters and queries that you can run against your logs.
As always, stay tuned to the blog for more updates to our developer documentation for instructions on how to get started with log retrieval. If you’re interested in joining the beta, please email [email protected].
Message queues are a fundamental building block of cloud applications—and today the Cloudflare Queues open beta brings queues to every developer building for Region: Earth. Cloudflare Queues follows Cloudflare Workers and Cloudflare R2 in a long line of innovative services built for the Workers Developer Platform, enabling developers to build more complex applications without configuring networks, choosing regions, or estimating capacity. Best of all, like many other Cloudflare services, there are no egregious egress charges!
If you’ve ever purchased something online and seen a message like “you will receive confirmation of your order shortly,” you’ve interacted with a queue. When you completed your order, your shopping cart and information were stored and the order was placed into a queue. At some later point, the order fulfillment service picks and packs your items and hands it off to the shipping service—again, via a queue. Your order may sit for only a minute, or much longer if an item is out of stock or a warehouse is busy, and queues enable all of this functionality.
Message queues are great at decoupling components of applications, like the checkout and order fulfillment services for an ecommerce site. Decoupled services are easier to reason about, deploy, and implement, allowing you to ship features that delight your customers without worrying about synchronizing complex deployments.
Queues also allow you to batch and buffer calls to downstream services and APIs. This post shows you how to enroll in the open beta, walks you through a practical example of using Queues to build a log sink, and tells you how we built Queues using other Cloudflare services. You’ll also learn a bit about the roadmap for the open beta.
Getting started
Enrolling in the open beta
Open the Cloudflare dashboard and navigate to the Workers section. Select Queues from the Workers navigation menu and choose Enable Queues Beta.
Review your order and choose Proceed to Payment Details.
Note: If you are not already subscribed to a Workers Paid Plan, one will be added to your order automatically.
Enter your payment details and choose Complete Purchase. That’s it – you’re enrolled in the open beta! Choose Return to Queues on the confirmation page to return to the Cloudflare Queues home page.
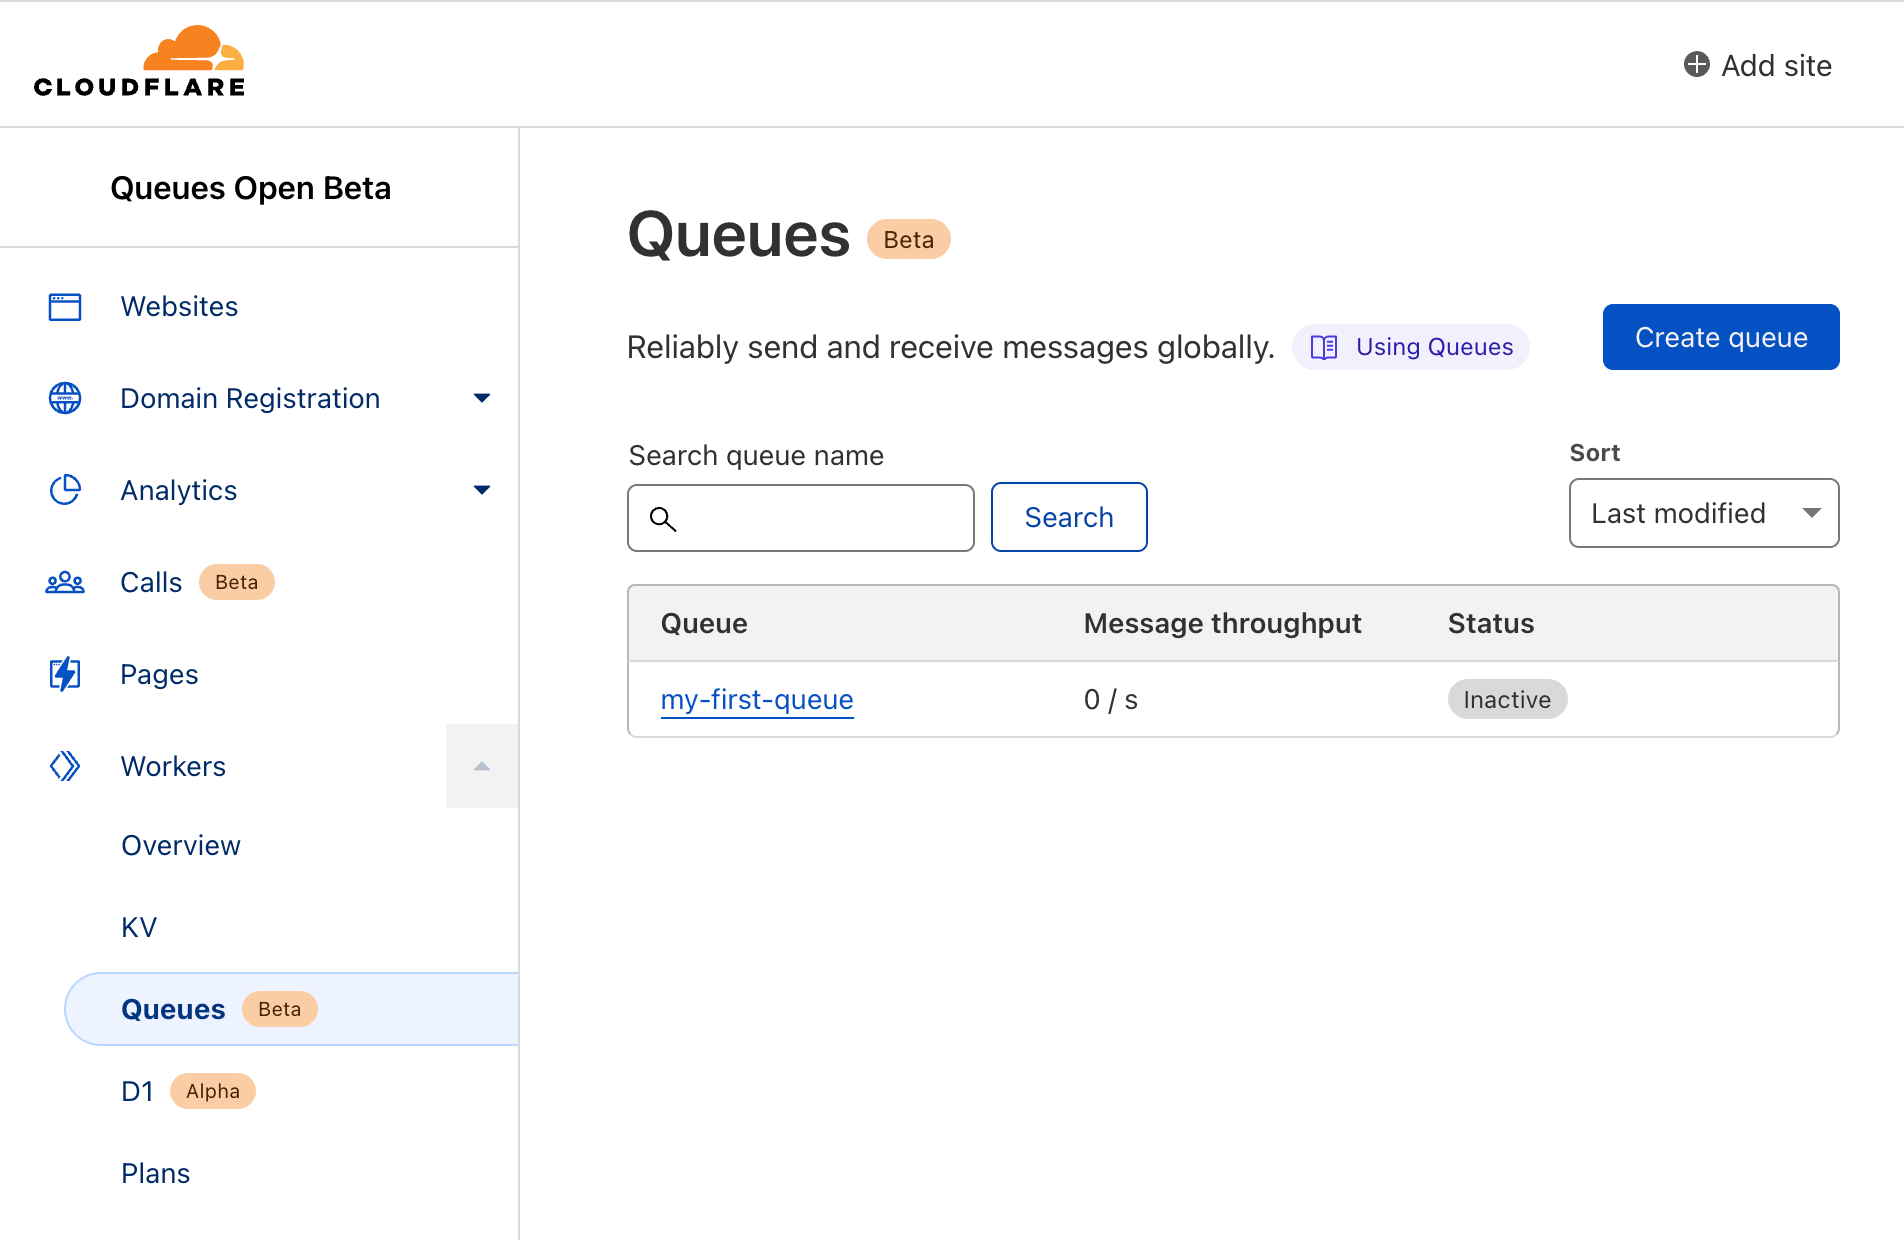
Creating your first queue
After enabling the open beta, open the Queues home page and choose Create Queue. Name your queue `my-first-queue` and choose Create queue. That’s all there is to it!
The dash displays a confirmation message along with a list of all the queues in your account.
Note: As of the writing of this blog post each account is limited to ten queues. We intend to raise this limit as we build towards general availability.
Managing your queues with Wrangler
You can also manage your queues from the command line using Wrangler, the CLI for Cloudflare Workers. In this section, you build a simple but complete application implementing a log aggregator or sink to learn how to integrate Workers, Queues, and R2.
Setting up resources To create this application, you need access to a Cloudflare Workers account with a subscription plan, access to the Queues open beta, and an R2 plan.
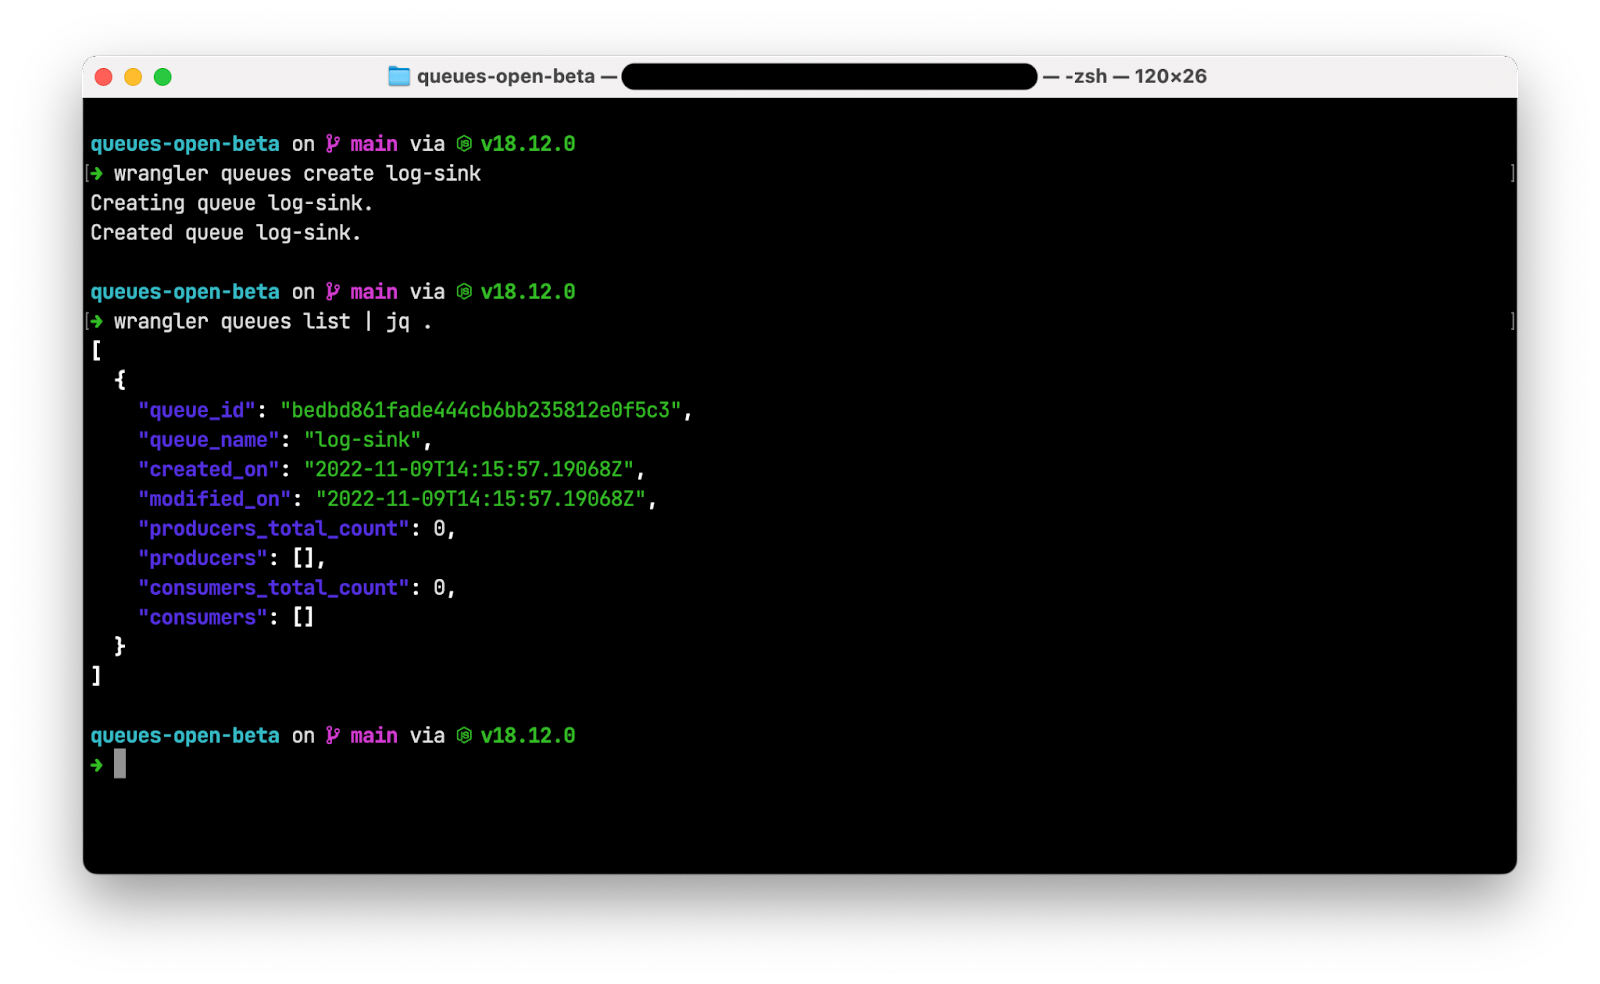
Install and authenticate Wrangler then run wrangler queues create log-sink from the command line to create a queue for your application.
Run wrangler queues list and note that Wrangler displays your new queue.
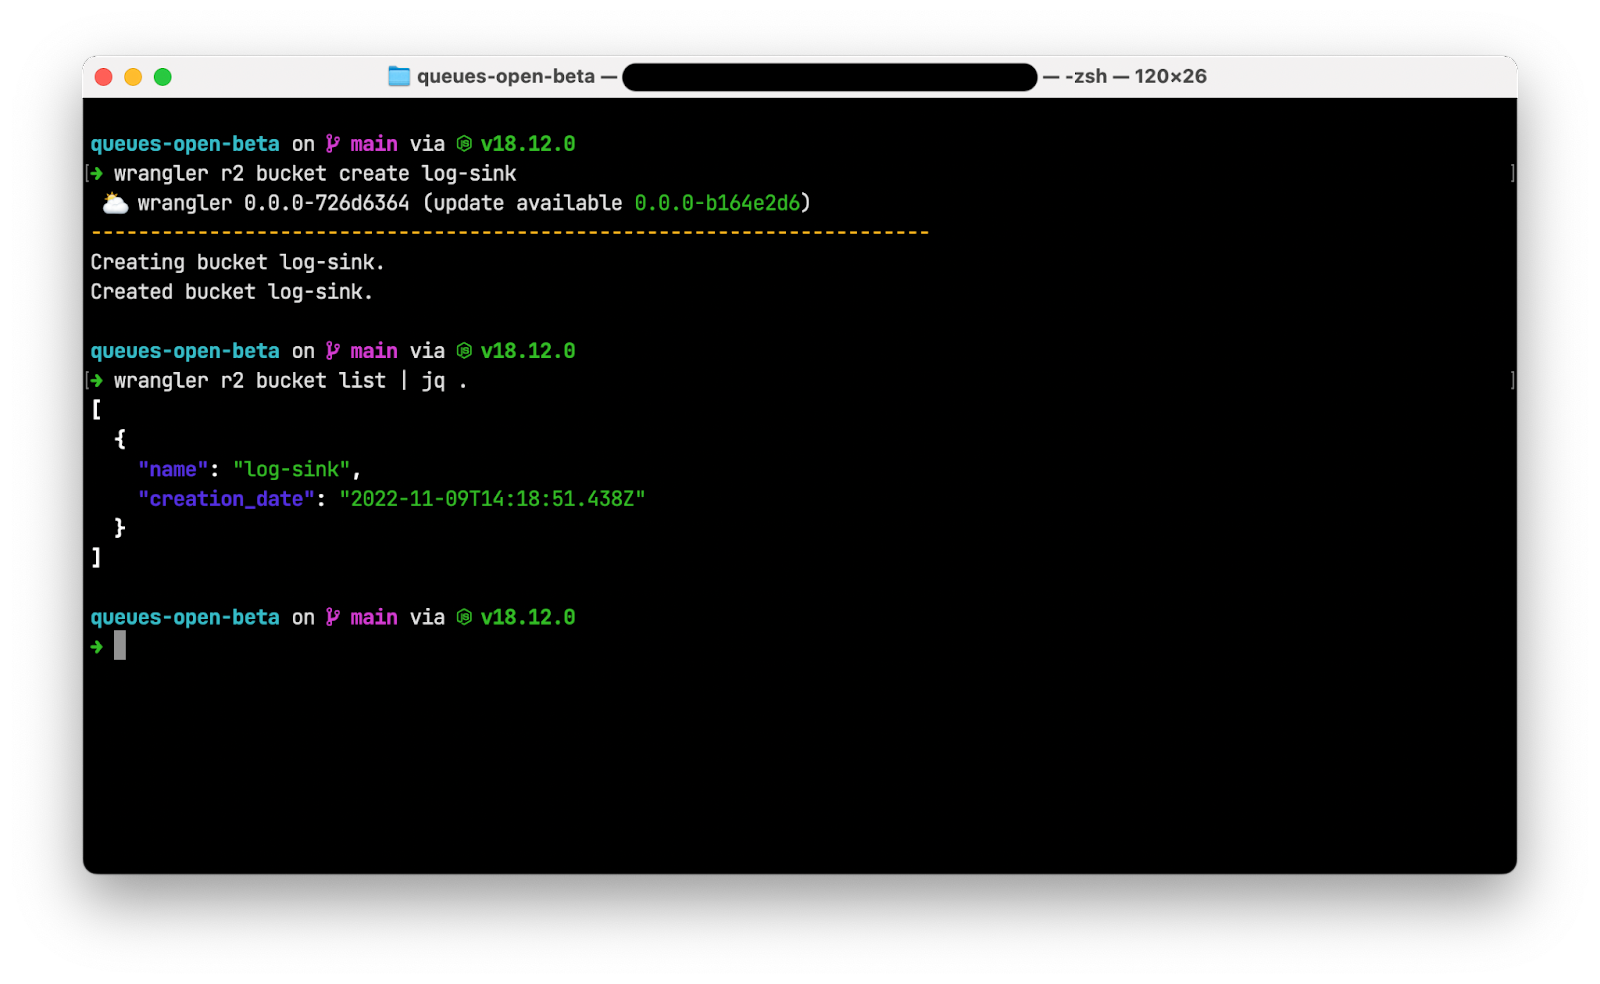
Note: The following screenshots use the jq utility to format the JSON output of wrangler commands. You do not need to install jq to complete this application.
Finally, run wrangler r2 bucket create log-sink to create an R2 bucket to store your aggregated logs. After the bucket is created, run wrangler r2 bucket list to see your new bucket.
Creating your Worker Next, create a Workers application with two handlers: a fetch() handler to receive individual incoming log lines and a queue() handler to aggregate a batch of logs and write the batch to R2.
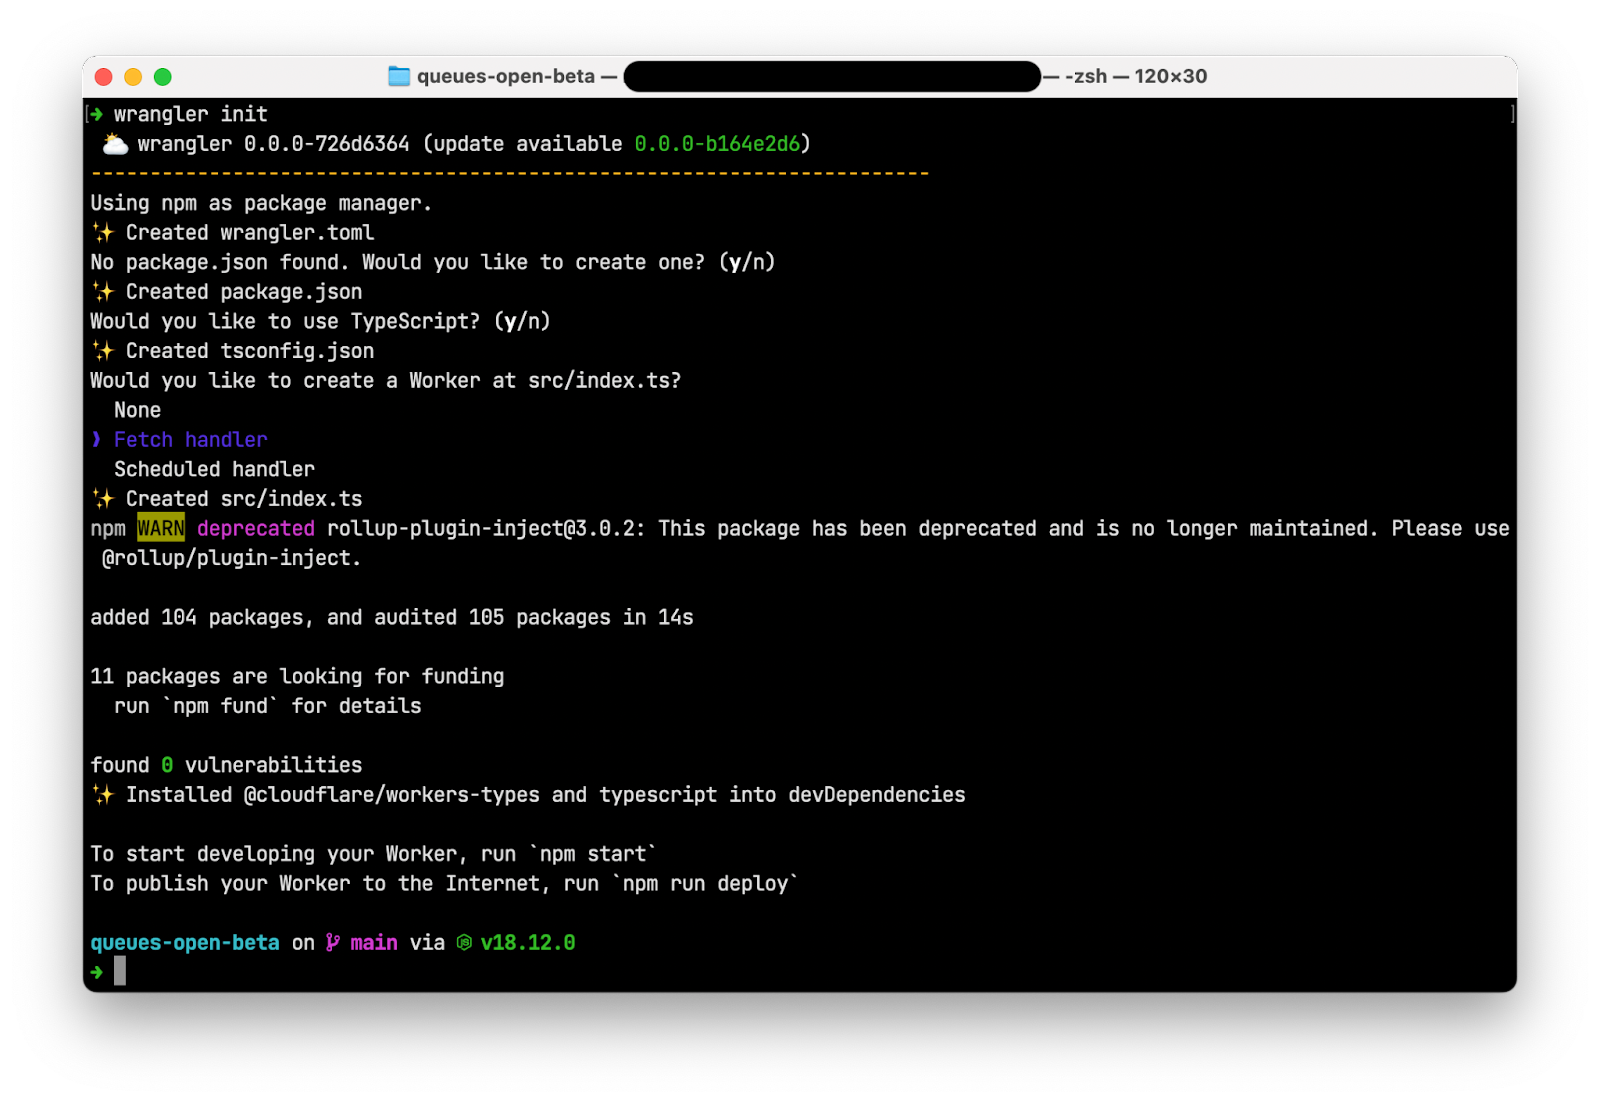
In an empty directory, run wrangler init to create a new Cloudflare Workers application. When prompted:
Choose “y” to create a new package.json
Choose “y” to use TypeScript
Choose “Fetch handler” to create a new Worker at src/index.ts
Open wrangler.toml and replace the contents with the following:
The [[queues.producers]] section creates a producer binding for the Worker at src/index.ts called BUFFER that refers to the log-sink queue. This Worker can place messages onto the log-sink queue by calling await env.BUFFER.send(log);
The [[queues.consumers]] section creates a consumer binding for the log-sink queue for your Worker. Once the log-sink queue has a batch ready to be processed (or consumed), the Workers runtime will look for the queue() event handler in src/index.ts and invoke it, passing the batch as an argument. The queue() function signature looks as follows:
The final binding in your wrangler.toml creates a binding for the log-sink R2 bucket that makes the bucket available to your Worker via env.LOG_BUCKET.
src/index.ts
Open src/index.ts and replace the contents with the following code:
The export interface Env section exposes the two bindings you defined in wrangler.toml: a queue named BUFFER and an R2 bucket named LOG_BUCKET.
The fetch() handler transforms the request body into JSON, adds the body to the BUFFER queue, then returns an HTTP 200 response with the message Success!
The `queue()` handler receives a batch of messages that each contain log entries, iterates through concatenating each log into a string buffer, then writes that buffer to the LOG_BUCKET R2 bucket using the current timestamp as the filename.
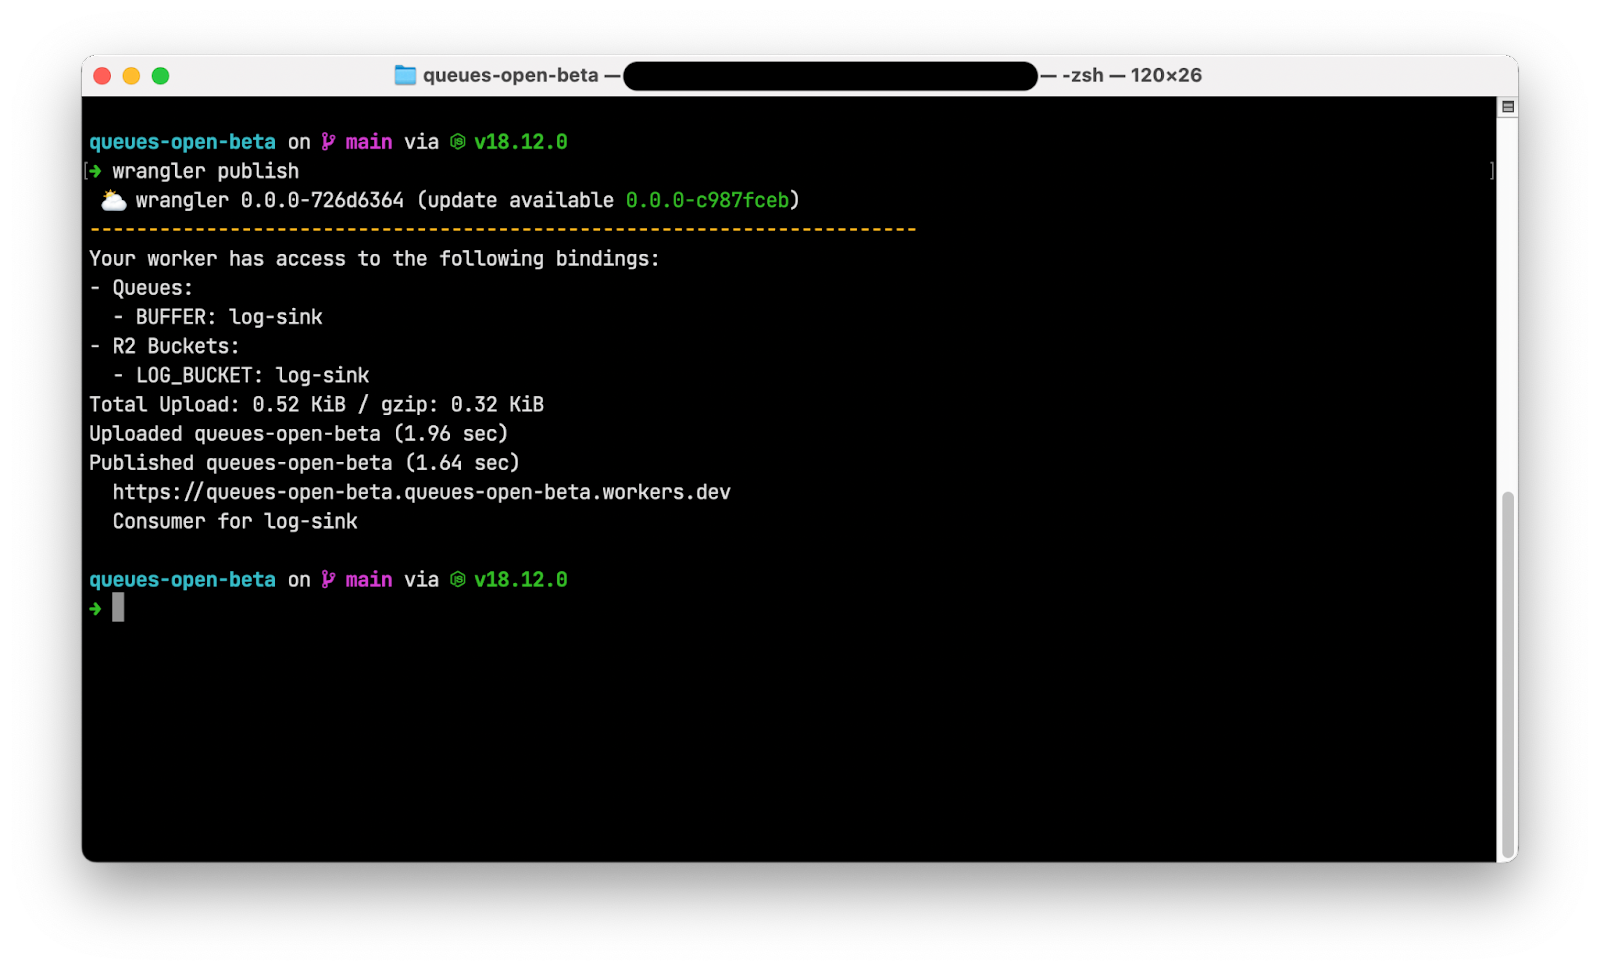
Publishing and running your application To publish your log sink application, run wrangler publish. Wrangler packages your application and its dependencies and deploys it to Cloudflare’s global network.
Note that the output of wrangler publish includes the BUFFER queue binding, indicating that this Worker is a producer and can place messages onto the queue. The final line of output also indicates that this Worker is a consumer for the log-sink queue and can read and remove messages from the queue.
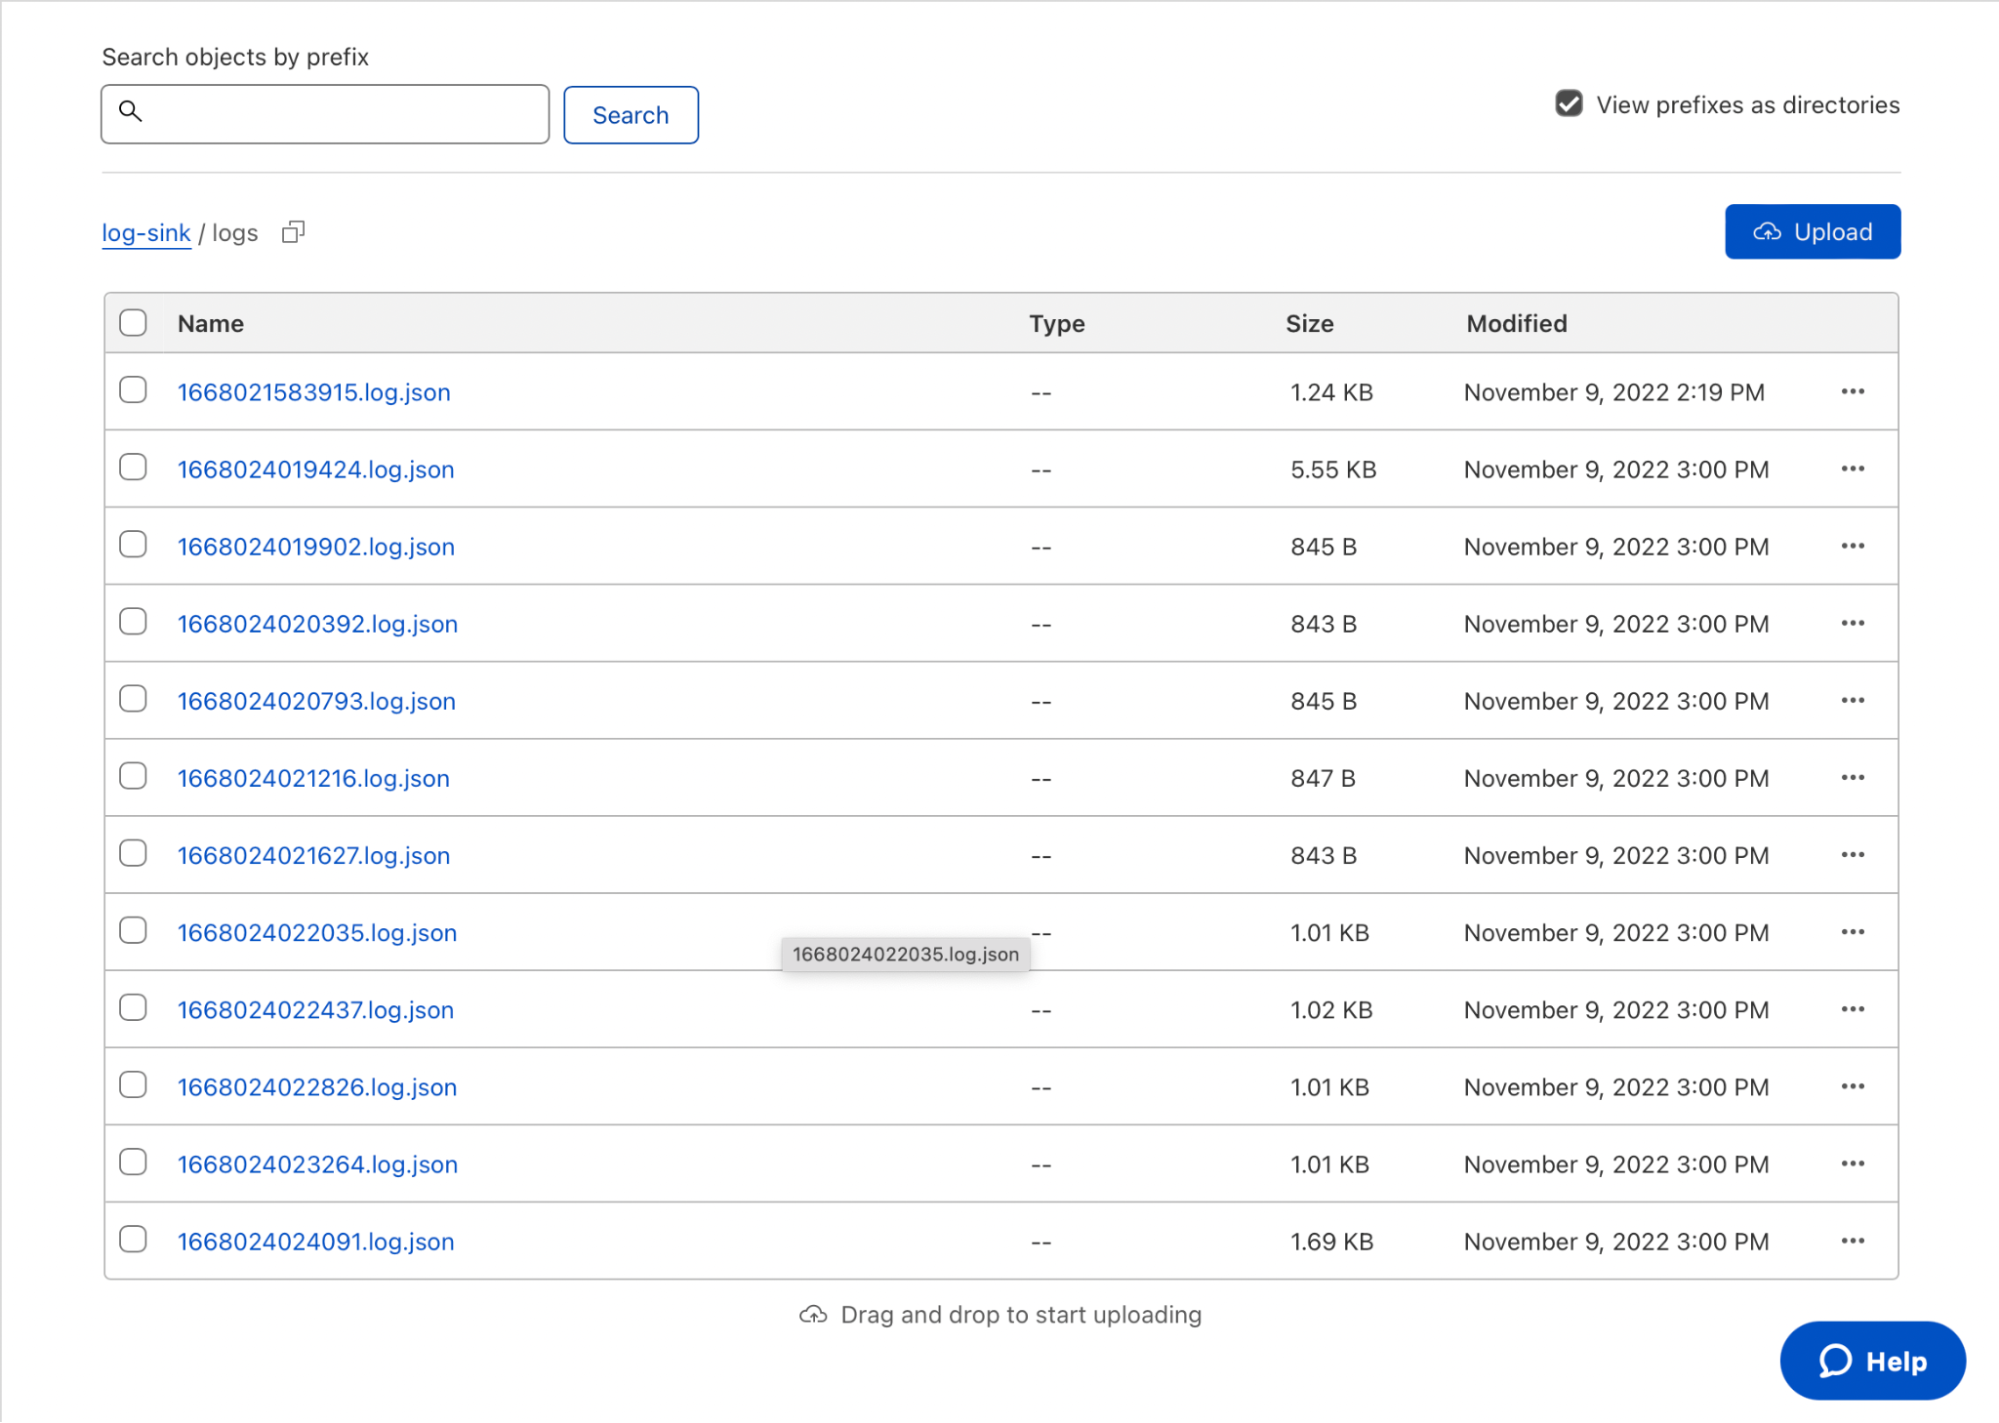
Use your favorite API client, like curl, httpie, or Postman, to send JSON log entries to the published URL for your Worker via HTTP POST requests. Navigate to your log-sink R2 bucket in the Cloudflare dashboard and note that the logs prefix is now populated with aggregated logs from your request.
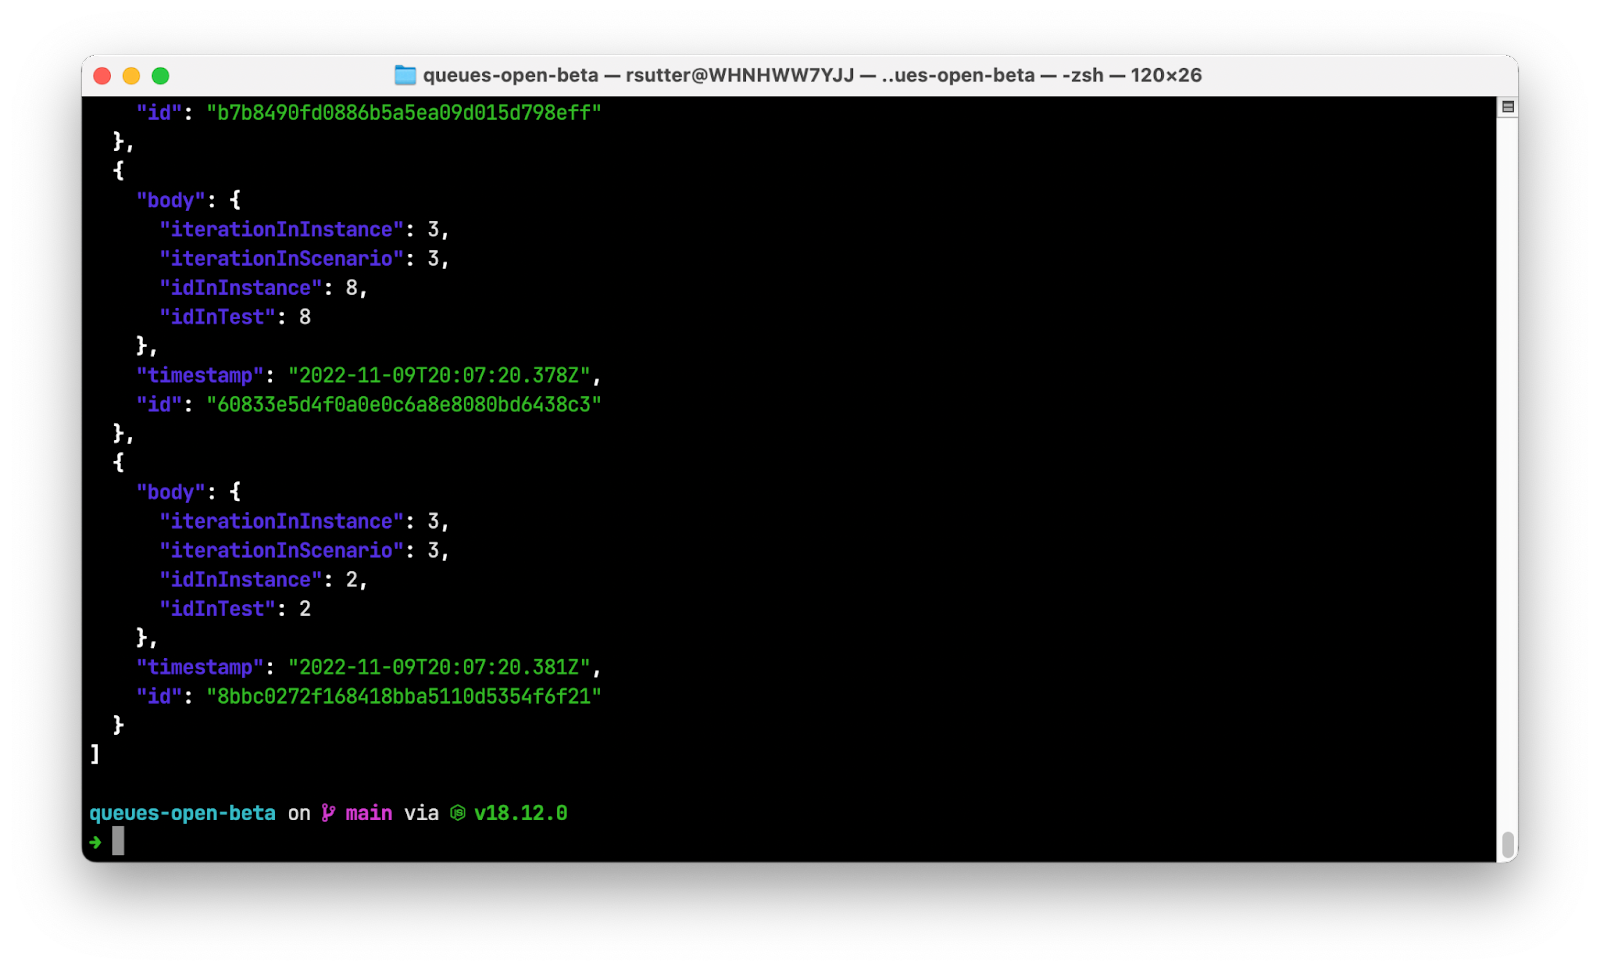
Download and open one of the logfiles to view the JSON array inside. That’s it – with fewer than 45 lines of code and config, you’ve built a log aggregator to ingest and store data in R2!
Buffering R2 writes with Queues in the real world
In the previous example, you create a simple Workers application that buffers data into batches before writing the batches to R2. This reduces the number of calls to the downstream service, reducing load on the service and saving you money.
UUID.rocks, the fastest UUIDv4-as-a-service, wanted to confirm whether their API truly generates unique IDs on every request. With 80,000 requests per day, it wasn’t trivial to find out. They decided to write every generated UUID to R2 to compare IDs across the entire population. However, writing directly to R2 at the rate UUIDs are generated is inefficient and expensive.
To reduce writes and costs, UUID.rocks introduced Cloudflare Queues into their UUID generation workflow. Each time a UUID is requested, a Worker places the value of the UUID into a queue. Once enough messages have been received, the buffered batch of JSON objects is written to R2. This avoids invoking an R2 write on every API call, saving costs and making the data easier to process later.
Like many of the Cloudflare services you use and love, we built Queues by composing other Cloudflare services like Workers and Durable Objects. This enabled us to rapidly solve two difficult challenges: securely invoking your Worker from our own service and maintaining a strongly consistent state at scale. Several recent Cloudflare innovations helped us overcome these challenges.
Securely invoking your Worker
In the Before Times (early 2022), invoking one Worker from another Worker meant a fresh HTTP call from inside your script. This was a brittle experience, requiring you to know your downstream endpoint at deployment time. Nested invocations ran as HTTP calls, passing all the way through the Cloudflare network a second time and adding latency to your request. It also meant security was on you – if you wanted to control how that second Worker was invoked, you had to create and implement your own authentication and authorization scheme.
Worker to Worker requests During Platform Week in May 2022, Service Worker Bindings entered general availability. With Service Worker Bindings, your Worker code has a binding to another Worker in your account that you invoke directly, avoiding the network penalty of a nested HTTP call. This removes the performance and security barriers discussed previously, but it still requires that you hard-code your nested Worker at compile time. You can think of this setup as “static dispatch,” where your Worker has a static reference to another Worker where it can dispatch events.
Dynamic dispatch As Service Worker Bindings entered general availability, we also launched a closed beta of Workers for Platforms, our tool suite to help make any product programmable. With Workers for Platforms, software as a service (SaaS) and platform providers can allow users to upload their own scripts and run them safely via Cloudflare Workers. User scripts are not known at compile time, but are dynamically dispatched at runtime.
With dynamic dispatch generally available, we now have the ability to discover and invoke Workers at runtime without the performance penalty of HTTP traffic over the network. We use dynamic dispatch to invoke your queue’s consumer Worker whenever a message or batch of messages is ready to be processed.
Consistent stateful data with Durable Objects
Another challenge we faced was storing messages durably without sacrificing performance. We took the design goal of ensuring that all messages were persisted to disk in multiple locations before we confirmed receipt of the message to the user. Again, we turned to an existing Cloudflare product—Durable Objects—which entered general availability nearly one year ago today.
Durable Objects are named instances of JavaScript classes that are guaranteed to be unique across Cloudflare’s entire network. Durable Objects process messages in-order and on a single-thread, allowing for coordination across messages and provide a strongly consistent storage API for key-value pairs. Offloading the hard problem of storing data durably in a distributed environment to Distributed Objects allowed us to reduce the time to build Queues and prepare it for open beta.
Open beta roadmap
Our open beta process empowers you to influence feature prioritization and delivery. We’ve set ambitious goals for ourselves on the path to general availability, most notably supporting unlimited throughput while maintaining 100% durability. We also have many other great features planned, like first-in first-out (FIFO) message processing and API compatibility layers to ease migrations, but we need your feedback to build what you need most, first.
Conclusion
Cloudflare Queues is a global message queue for the Workers developer. Building with Queues makes your applications more performant, resilient, and cost-effective—but we’re not done yet. Join the Open Beta today and share your feedback to help shape the Queues roadmap as we deliver application integration services for the next generation cloud.
While scaling our new Feature Flagging product DevCycle, we’ve encountered an interesting challenge: our Cloudflare Workers-based infrastructure can handle way more instantaneous load than our traditional AWS infrastructure. This led us to rethink how we design our infrastructure to always use Cloudflare Workers for everything.
The origin of DevCycle
For almost 10 years, Taplytics has been a leading provider of no-code A/B testing and feature flagging solutions for product and marketing teams across a wide range of use cases for some of the largest consumer-facing companies in the world. So when we applied ourselves to build a new engineering-focused feature management product, DevCycle, we built upon our experience using Workers which have served over 140 billion requests for Taplytics customers.
The inspiration behind DevCycle is to build a focused feature management tool for engineering teams, empowering them to build their software more efficiently and deploy it faster. Helping engineering teams reach their goals, whether it be continuous deployment, lower change failure rate, or a faster recovery time. DevCycle is the culmination of our vision of how teams should use Feature Management to build high-quality software faster. We’ve used DevCycle to build DevCycle, enabling us to implement continuous deployment successfully.
DevCycle architecture
One of the first things we asked ourselves when ideating DevCycle was how we could get out of the business of managing 1000’s of vCPUs worth of AWS instances and move our core business logic closer to our end-user devices. Based on our experience with Cloudflare Workers at Taplytics we knew we wanted it to be a core part of our future infrastructure for DevCycle.
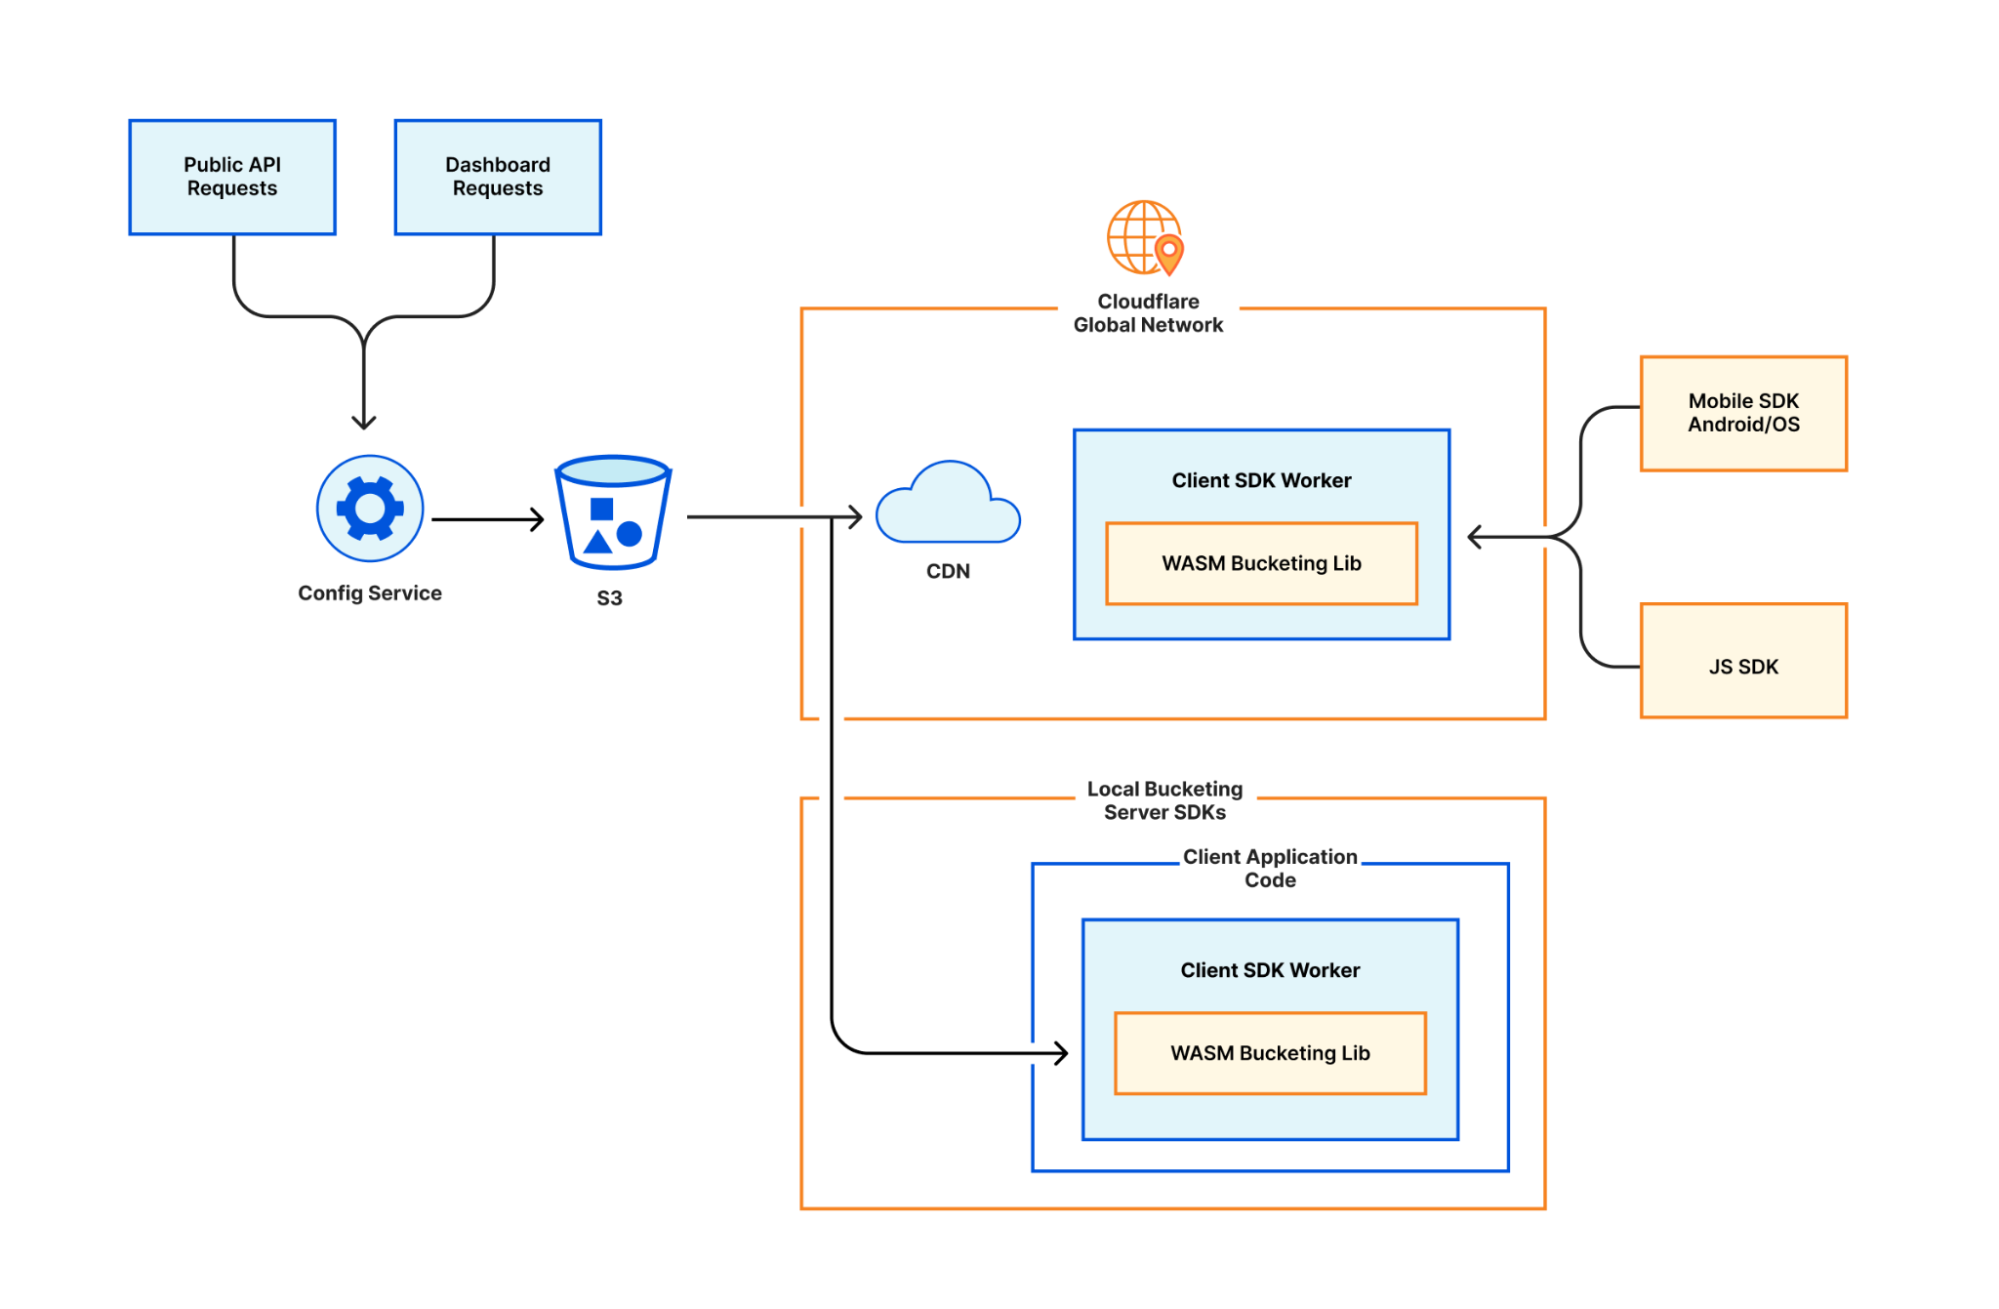
By using the global computing power of Workers and moving as much logic to the SDKs as possible with our local bucketing server-side SDKs, we were able to massively reduce or eliminate the latency of fetching feature flag configurations for our users. In addition, we used a shared WASM library across our Workers and local bucketing SDKs to dramatically reduce the amount of code we need to maintain per SDK, and increase the consistency of our platform. This architecture has also fundamentally changed our business’s cost structure to easily serve any customer of any scale.
The core architecture of DevCycle revolves around publishing and consuming JSON configuration files per project environment. The publishing side is managed in our AWS services, while Cloudflare manages the consumption of these config files at scale. This split in responsibilities allows for all high-scale requests to be managed by Cloudflare, while keeping our AWS services simple and low-scale.
“Workers are breaking our events pipeline”
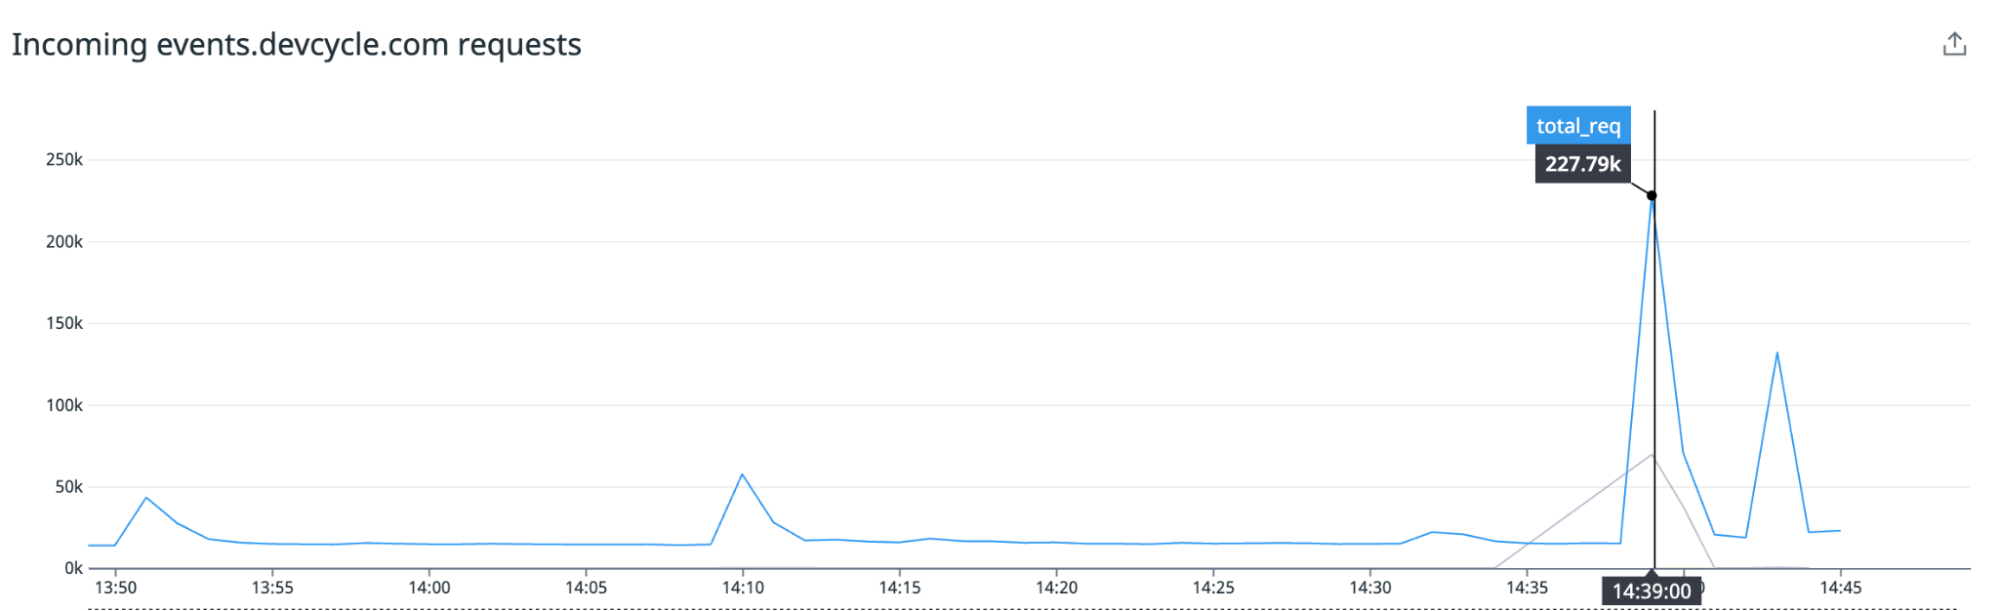
One of the primary challenges as a feature management platform is that we don’t have direct control over the load from our customers’ applications using our SDKs; our systems need the ability to scale instantly to match their load. For example, we have a couple of large customers whose mobile traffic is primarily driven by push notifications, which causes massive instantaneous spikes in traffic to our APIs in the range of 10x increases in load. As you can imagine, any traditional auto-scaled API service and the load balancer cannot manage that type of increase in load. Thus, our choices are to dramatically increase the minimum size of our cluster and load balancer to handle these unknown load spikes, accept that some requests will be rate-limited, or move to an architecture that can handle this load.
Given that all our SDK API requests are already served with Workers, they have no problem scaling instantly to 10x+ their base load. Sadly we can’t say the same about the traditional parts of our infrastructure.
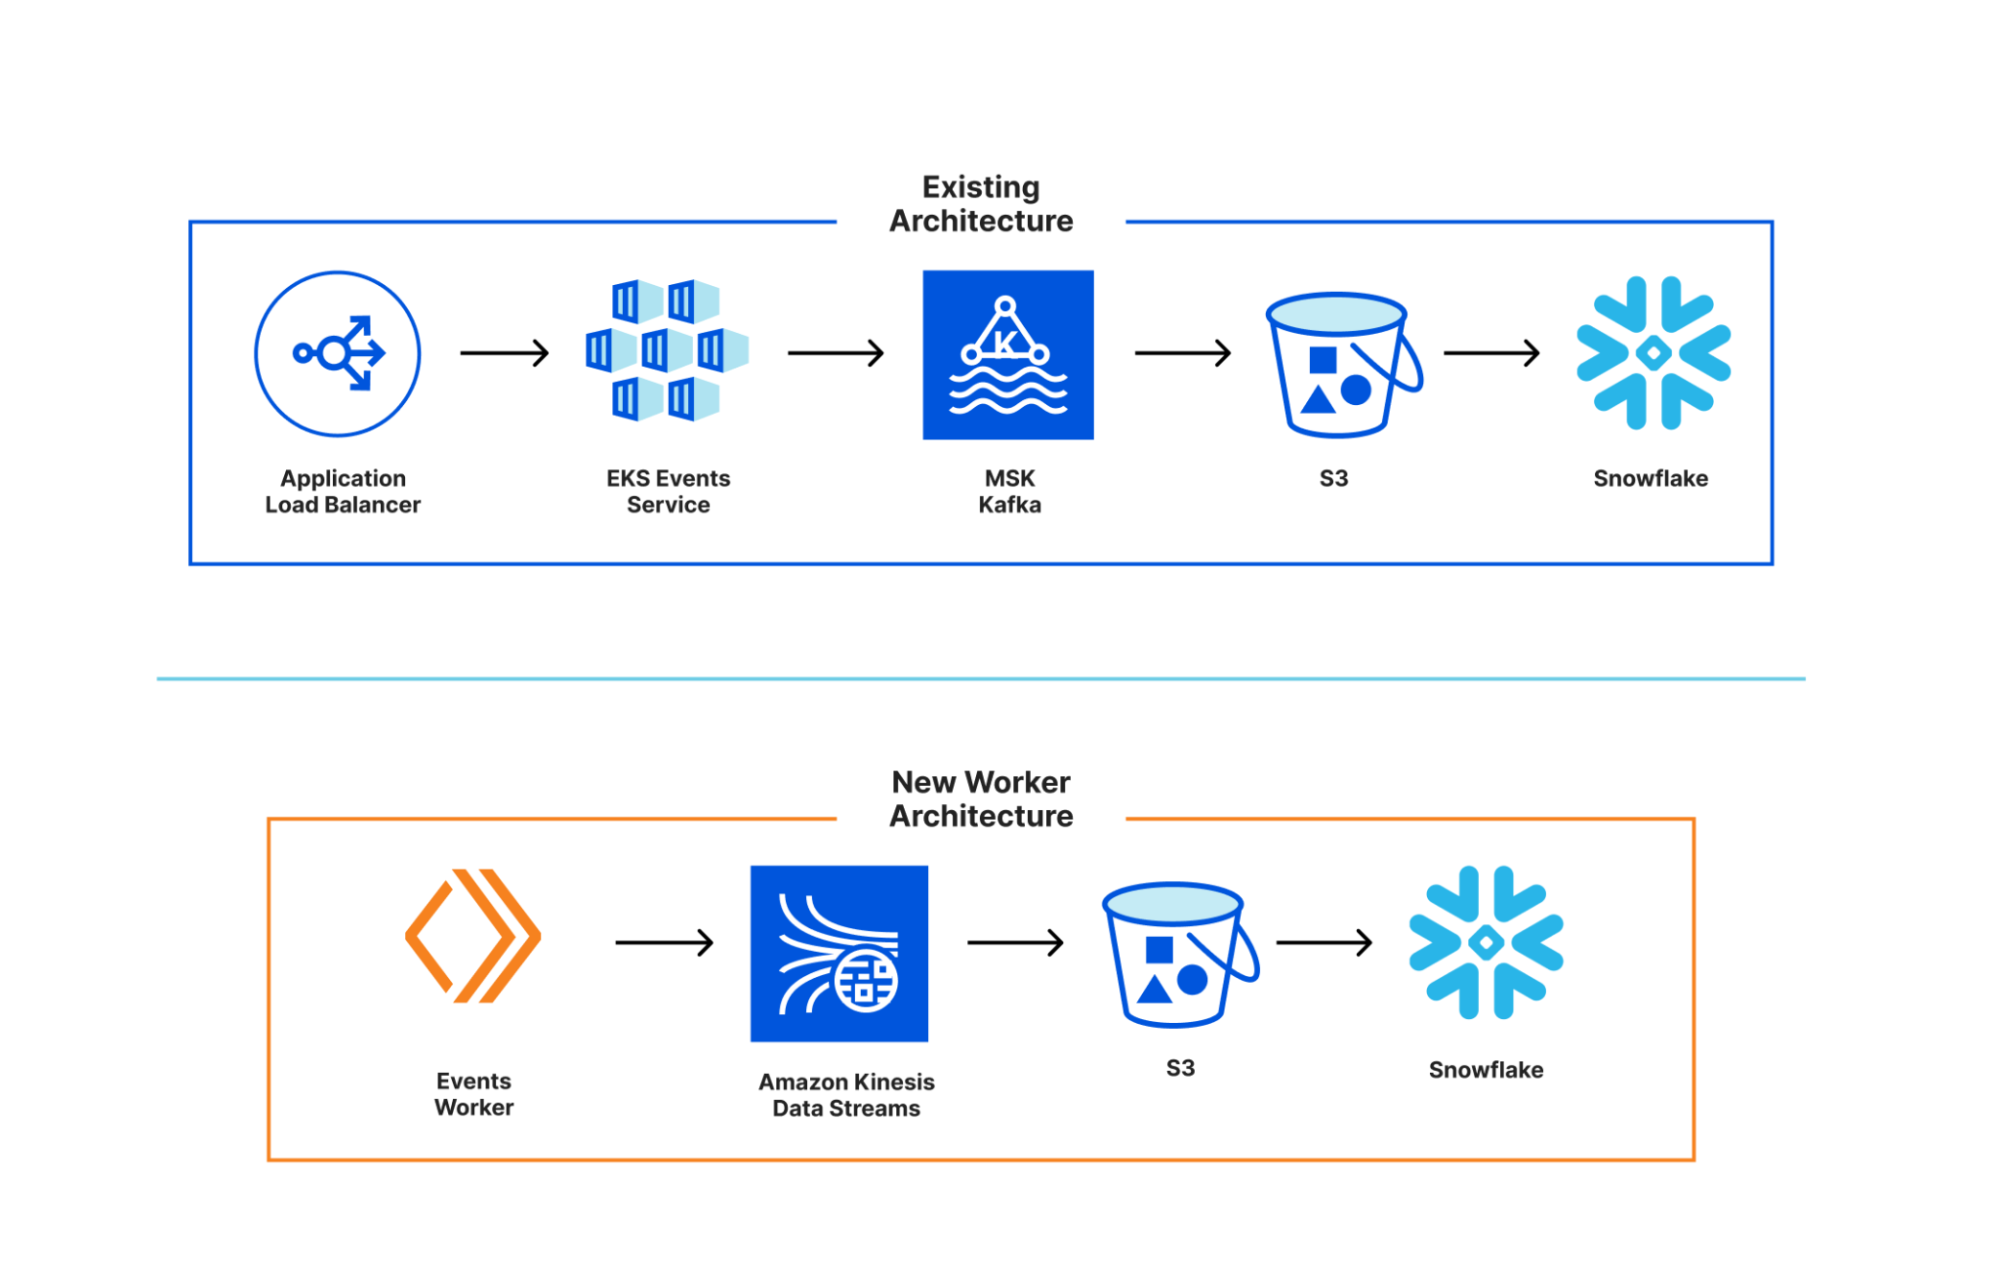
For each feature flag configuration request to a Worker, a corresponding events request is sent to our AWS events infrastructure. The events are received by our events API container in Kubernetes, where they are then published to Kafka and eventually ingested by Snowflake. While Cloudflare Workers have no problem handling instantaneous spikes in feature flag requests, the events system can’t keep up. Our cluster and events API containers need to be scaled up faster to prevent the existing instances from being overwhelmed. Even the load balancer has issues accepting the sudden increase. Cloudflare Workers just work too well in comparison to EC2 instances + EKS.
To solve this issue we are moving towards a new events Cloudflare Worker which will be able to handle the instantaneous events load from these requests and make use of the Kinesis Data Firehose to write events to our existing S3 bucket which is ingested by Snowflake. In the future, we look forward to testing out Cloudflare Queues writing to R2 once a Snowflake connector has been created. This architecture should allow us to ingest events at almost any scale and withstand instantaneous traffic spikes with a predictable and efficient cost structure.
Building without a database next to your code
Workers provide many benefits, including fast response times, infinite scalability, serverless architecture, and excellent up-time performance. However, if you want to see all these benefits, you need to architect your Workers to assume that you don’t have direct access to a centralized SQL / NoSQL database (or D1) like you would with a traditional API service. For example, suppose you build your workers to require reaching out to a database to fetch and update user data every time a request is made to your Workers. In that case, your request latency will be tied to the geographic distance between your Worker and the database plus the latency of the database. In addition, your Workers will be able to scale significantly beyond the number of database connections you can support, and your uptime will be tied to the uptime of your external database. Therefore, when architecting your systems to use Workers, we advise relying primarily on data sent as part of the API request and cacheable data on Cloudflare’s global network.
Cloudflare provides multiple products and services to help with data on their global network:
However, the lowest latency way of retrieving data from within a Worker is limited by a minimum 60-second TTL. So you’ll need to be ok with cached data that is 60 seconds stale.
Durable Objects: “provide low-latency coordination and consistent storage for the Workers platform through two features: global uniqueness and a transactional storage API.”
Ability to store user-level information closer to the end user.
Unfamiliar worker interface for accessing data for developers with SQL / NoSQL experience.
Each of these tools that Cloudflare provides has made building APIs far more accessible than when Workers launched initially; however, each service has aspects which need to be accounted for when architecting your systems. Being an open platform, you can also access any publically available database you want from a Worker. For example, we are making use of Macrometa for our EdgeDB product built into our Workers to help customers access their user data.
The predictable cost structure of Workers
One of the greatest advantages of moving most of our workloads towards Cloudflare Workers is the predictable cost structure that can scale 1:1 with our request loads and can be easily mapped to usage-based billing for our customers. In addition, we no longer have to run excess EC2 instances to handle random spikes in load, just in case they happen.
Too many SaaS services have opaque billing based on max usage or other metrics that don’t relate directly to their costs. Moving from our legacy AWS architecture with high fixed costs like databases and caching layers to Workers has resulted in our infrastructure spending is directly tied to using our APIs and SDKs. For DevCycle, this architecture has been over ~5x more cost-efficient to operate.
The future of DevCycle and Cloudflare
With DevCycle we will continue to invest in leveraging serverless computing and moving our core business logic as close to our users as possible, either on Cloudflare’s global network or locally within our SDKs. We’re excited to integrate even more deeply with the Cloudflare developer platform as new services evolve. We already see future use cases for R2, Queues and Durable Objects and look forward to what’s coming next from Cloudflare.
Earlier this year, we announced our participation in a new W3C Community Group for the advancement of Web-interoperable API standards. Since then, this new WinterCG has been hard at work identifying the common API standards around which all JavaScript runtimes can build. Today I just want to give a peek at some work the WinterCG has been doing; and show off some of the improvements we have been making in the Workers runtime to increase alignment with Web Platform standards around event handling, task cancellation using AbortController, text encoding and decoding, URL parsing and pattern matching, and streams support.
The WinterCG Minimum Common Web Platform API
Right at the start of the WinterCG activity, the group took some time to evaluate and compare the various non-browser JavaScript runtimes such as Node.js, Deno, Bun, and Workers with the purpose of identifying the Web Platform APIs they all had in common. Following a very simple criteria, we looked at the standard APIs that were already implemented and supported by at least two of these runtimes and compiled those into a list that the WinterCG calls the “Minimum Common Web Platform API“. This list will serve as the basis for what the community group defines as the minimum set of Web Platform APIs that should be implemented consistently across runtimes that claim to be “Web-interoperable”.
Today, we are happy to say that the Workers runtime has compliant or nearly compliant implementations of every one of these WinterCG Minimum Common Web Platform APIs. Some of these APIs intentionally diverge from the standards either due to backwards compatibility concerns, Workers-specific features, or performance optimizations. Other APIs diverge still because we are still in the process of updating them to align with the specifications.
Improving standards compliance in the Workers runtime
The Workers runtime has, from the beginning, had the mission to align its developer experience with JavaScript and Web Platform standards as much as possible. Over the past year we have worked hard to continue advancing that mission forward both by improving the standards-compliance of existing APIs such as Event, EventTarget, URL, and streams; and the introduction of new Web Platform APIs such as URLPattern, encoding streams, and compression streams.
Event and EventTarget
The Workers runtime has provided an implementation of the Event and EventTarget Web Platform APIs from the very beginning. These were, however, only limited implementations of what the WHATWG DOM specification defines. Specifically, Workers had only implemented the bare minimum of the Event API that it itself needed to operate.
Today, the Event and EventTarget implementations in Workers provide a more complete implementation.
Let’s look at the official definition of Event as defined by the WHATWG DOM standard:
Web Platform API specifications are always written in terms of a definition language called Web IDL. Every attribute defined in the interface is a property that is exposed on the object. Event objects, then, are supposed to have properties like type, target, srcElement, currentTarget, bubbles, cancelable, returnValue, defaultPrevented, composed, isTrusted, and timeStamp. They are also expected to have methods such as composedPath(), stopPropagation(), and stopImmediatePropagation(). Because most of these were not immediately needed by Workers, most were not provided originally.
Today, all standard, non-legacy properties and methods defined by the specification are available for use:
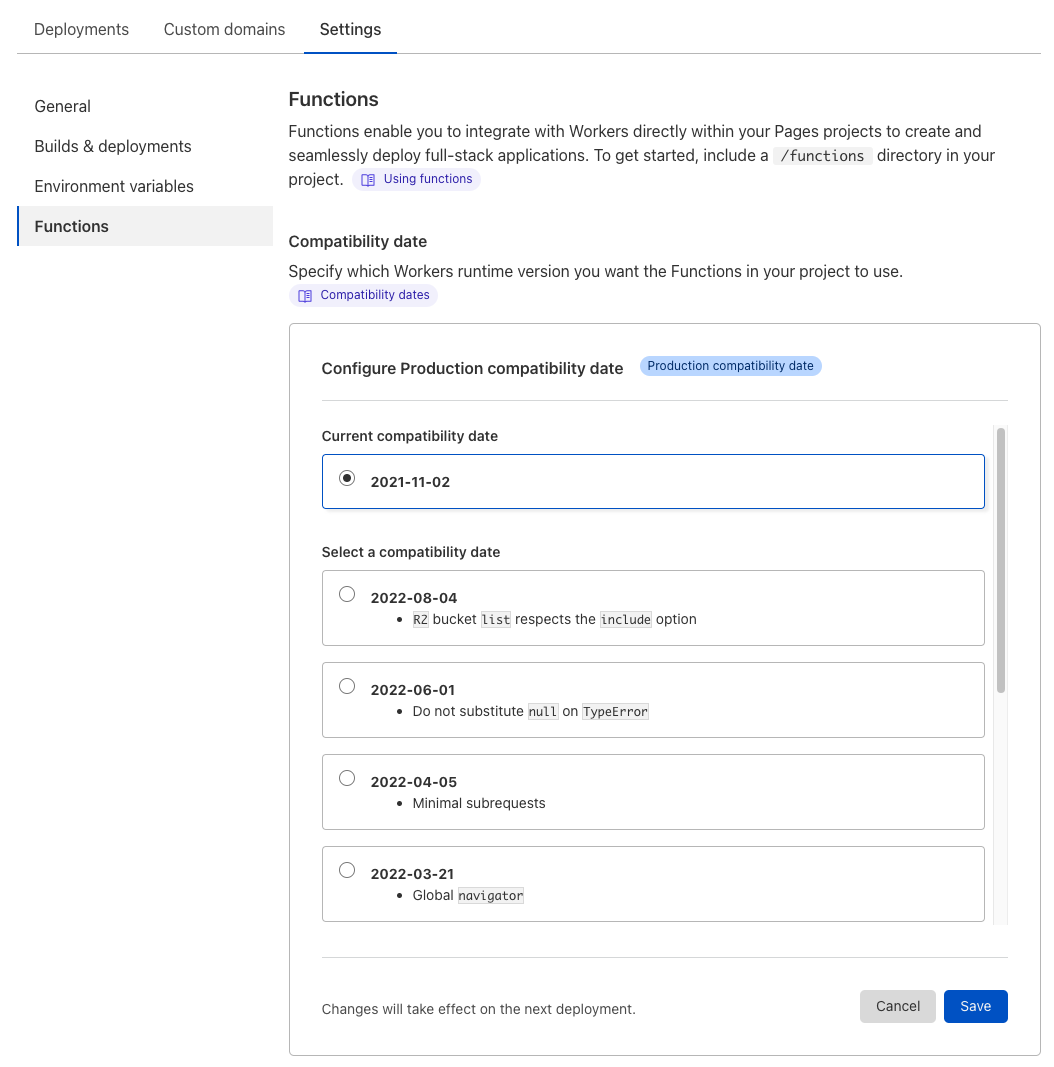
While we were at it, we also fixed a long standing bug in the implementation of Event that prevented user code from properly subclassing the Event object to create their own custom event types. This change is protected by a compatibility flag that is now enabled by default for all Workers using a compatibility date on or past 2022-01-31.
  class MyEvent extends Event {
    constructor() {
      super('my-event')
    }

    get type() { return super.type.toUpperCase() }
  }

  const myEvent = new MyEvent();
  // Previously, this would print "my-event" instead of "MY-EVENT" as expected.
  console.log(myEvent.type);
The EventTarget implementation has also been updated to support once handlers (event handlers that are triggered at-most once then automatically unregistered), cancelable handlers (using AbortSignal), and event listener objects, all in line with the standard.
Once handlers are key for preventing memory leaks in your applications when you know that a particular event is only ever going to be emitted once, or whenever you only care about handling it once. The stored reference to the function or object that is handling the event is removed immediately upon the first invocation, allowing the memory to be garbage collected.
Using a cancelable event handler
  const ac = new AbortController();

  addEventListener('foo', (event) => {
    console.log('not printed at all');
  }, {
    signal: ac.signal
  });

  ac.abort();

  dispatchEvent(new Event('foo'));
Using an event listener object
While passing a function to addEventListener() is the most common case, the standard actually allows an event listener to be an object with a handleEvent() method as well.
As illustrated in the cancelable event example above, we have also introduced an implementation of the AbortController and AbortSignal APIs into Workers. These provide a standard, and interoperable way of signaling cancellation of several kinds of tasks.
The AbortController/AbortSignal pattern is straightforward: An AbortSignal is just a type of EventTarget that will emit a single “abort” event when it is triggered:
  const ac = new AbortController();

  ac.signal.addEventListener('abort', (event) => {
    console.log(event.reason);  // 'just because'
  }, { once: true });

  ac.abort('just because');
The AbortController is used to actually trigger the abort event, optionally with a reason argument that is passed on to the event. The reason is typically an Error object but can be any JavaScript value.
The AbortSignal can only be triggered once, so the “abort” event should only ever be emitted once.
It is also possible to create AbortSignals that timeout after a specified period of time:
const signal = AbortSignal.timeout(10);
Or an AbortSignal that is pre-emptively triggered immediately on creation (these will never actually emit the “abort” event):
const signal = AbortSignal.abort('for reasons');
Currently, within Workers, AbortSignal and AbortController has been integrated with the EventTarget, fetch(), and streams APIs in alignment with the relevant standard specifications for each.
Using AbortSignal to cancel a fetch()
  const ac = new AbortController();

  const res = fetch('https://example.org', {
    signal: ac.signal
  });

  ac.abort(new Error('canceled'))

  try {
    await res;
  } catch (err) {
    console.log(err);
  }
TextEncoderStream and TextDecoderStream
The Workers runtime has long provided basic implementations of the TextEncoder and TextDecoder APIs. Initially, these were limited to only supporting encoding and decoding of UTF-8 text. The standard definition of TextDecoder, however, defines a much broader range of text encodings that are now fully supported by the Workers implementation. Per the standard, TextEncoder currently only supports UTF-8.
In addition to supporting the full range of encodings defined by the standard, Workers also now provides implementations of the TextEncoderStream and TextDecoderStream, which provide TransformStream implementations that apply encoding and decoding to streaming data:
const ds = new DecompressionStream('gzip');
const decompressedStream = blob.stream().pipeThrough(ds);

const cs = new CompressionStream('gzip');
const compressedStream = blob.stream().pipeThrough(cs);
These are TransformStream implementations that fully conform to the standard definitions. Use of the compression streams does not require a compatibility flag to enable.
URL and URLPattern
Similar to Event, there has been an implementation of the Web Platform standard URL API available within Workers from nearly the beginning. But also like Event, the implementation was not entirely compatible with the standard.
The incompatibilities were subtle, for instance, in the original implementation, the URL string “https://a//b//c//” would be parsed incorrectly as “https://a/b/c” (note that the extra empty path segments are removed) whereas the standard parsing algorithm would produce “https://a//b//c/” as a result. Such inconsistent results were causing interoperability issues with JavaScript written to run across multiple JavaScript runtimes and needed to be fixed.
A new implementation of the URL parsing algorithm has been provided, and as of October 31, 2022 it has been enabled by default for all newly deployed Workers. Older Workers can begin using the new implementation by updating their compatibility dates to 2022-10-31 or by enabling the url_standard compatibility flag.
Along with the updated URL implementation, Workers now provides an implementation of the standard URLPattern API.
URLPattern provides a regular-expression-like syntax for matching a URL string against a pattern. For instance, consider this example taken from the MDN documentation for URLPattern:
  // Matching a pathname
  let pattern1 = new URLPattern('https://example.com/books/:id')
  // same as
  let pattern2 = new URLPattern(
    '/books/:id',
    'https://example.com',
  );
  // or
  let pattern3 = new URLPattern({
    protocol: 'https',
    hostname: 'example.com',
    pathname: '/books/:id',
  });
  // or
  let pattern4 = new URLPattern({
    pathname: '/books/:id',
    baseURL: 'https://example.com',
  });
ReadableStream, WritableStream, and TransformStream
Last, but absolutely not least, our most significant effort over the past year has been providing new standards compliant implementations of the ReadableStream, WritableStream, and TransformStream APIs.
The Workers runtime has always provided an implementation of these objects but they were never fully conformant to the standard. User code was not capable of creating custom ReadableStream and WritableStream instances, and TransformStreams were limited to simple identity pass-throughs of bytes. The implementations have been updated now to near complete compliance with the standard (near complete because we still have a few edge cases and features we are working on).
The new streams implementation will be enabled by default in all new Workers as of November 30, 2022, or can be enabled earlier using the streams_enable_constructors and transformstream_enable_standard_constructor compatibility flags.
Creating a custom ReadableStream
async function handleRequest(request) {
  const enc = new TextEncoder();

  const rs = new ReadableStream({
    pull(controller) {
      controller.enqueue(enc.encode('hello world'));
      controller.close();
    }
  });

  return new Response(rs);
}
The new implementation supports both “regular” and “bytes” ReadableStream types, supports BYOB readers, and includes performance optimizations for both tee() and pipeThrough().
It has always been possible in Workers to call new TransformStream() (with no arguments) to create a limited version of a TransformStream that only accepts bytes and only acts as a pass-through, passing the bytes written to the writer on to the reader without any modification.
That original implementation is now available within Workers using the IdentityTransformStream class.
  const { readable, writable } = new IdentityTransformStream();

  const writer = writable.getWriter();
  const reader = readable.getReader();

  const enc = new TextEncoder();
  const dec = new TextDecoder();

  writer.write(enc.encode("hello world"));

  const res = await reader.read();
  console.log(dec.decode(res.value));  // "hello world"
If your code is using new TransformStream() today as this kind of pass-through, the new implementation will continue to work except for one very important difference: the old, non-standard implementation of new TransformStream() supported BYOB reads on the readable side (i.e. readable.getReader({ mode: 'byob' })). The new implementation (enabled via a compatibility flag and becoming the default on November 30 ) does not support BYOB reads as required by the stream standard.
What’s next
It is clear that we have made a lot of progress in improving the standards compliance of the Workers runtime over the past year, but there is far more to do. Next we will be turning our attention to the implementation of the fetch() and WebSockets APIs, as well as actively seeking closer alignment with other runtimes through collaboration in the Web-interoperable Runtimes Community Group.
If you are interested in helping drive the implementation of Web Platform APIs forward, and advancing interoperability between JavaScript runtime environments, the Workers Runtime team at Cloudflare is hiring! Reach out, or see our open positions here.
Cloudflare Pages started its journey as a platform for static websites, but with last year’s addition of Pages Functions powered by Cloudflare Workers, the platform has progressed to support an even more diverse range of use cases. Pages Functions allows developers to sprinkle in small pieces of server-side code with its simple file-based routing, or, as we’ve seen with the adoption from other frameworks (namely SvelteKit, Remix and Qwik), Pages Functions can be used to power your entire full-stack app. The folks behind Remix previously talked about the advantages of adopting open standards, and we’ve seen this again with Next.js’ Edge Runtime.
Next.js’ Edge Runtime
Next.js’ Edge Runtime is an experimental mode that developers can opt into which results in a different type of application being built. Previously, Next.js applications which relied on server-side rendering (SSR) functionality had to be deployed on a Node.js server. Running a Node.js server has significant overhead, and our Cloudflare Workers platform was fundamentally built on a different technology, V8.
However, when Next.js introduced the Edge Runtime mode in June 2022, we saw the opportunity to bring this widely used framework to our platform. We’re very excited that this is being developed in coordination with the WinterCG standards to ensure interoperability across the various web platforms and to ensure that developers have the choice on where they run their business, without fearing any significant vendor lock-in.
It’s important to note that some existing Next.js apps built for Node.js won’t immediately work on Pages. If your application relies on any Node.js built-ins or long-running processes, then Pages may not support your app with today’s announcement as we’re working on expanding our support for Node.js.
However, we see the migration to the Edge Runtime as an effort that’s worthy of investment, to run your applications, well, on the edge! These applications are cheaper to run, respond faster to users and have the latest features that full-stack frameworks offer. We’re seeing increased interest in third-party npm packages and libraries that support standardized runtimes, and in combination with Cloudflare’s data products (e.g. KV, Durable Objects and D1), we’re confident that the edge is going to be the first place that people will want to deploy applications going forward.
Deploy your Next.js app to Cloudflare Pages
Let’s walk through an example, creating a new Next.js application that opts into this Edge Runtime and deploying it to Cloudflare Pages.
npx create-next-app@latest my-app
This will create a new Next.js app in the my-app folder. The default template comes with a traditional Node.js powered API route, so let’s update that to instead use the Edge Runtime.
Thanks to the Edge Runtime adopting the Web API standards, if you’ve ever written a Cloudflare Worker before, this might look familiar.
Next, we can update the global next.config.js configuration file to use the Edge Runtime. This will enable us to use the getServerSideProps() API and server-side render (SSR) our webpages.
Finally, we’re ready to deploy the project. Publish it to a GitHub or GitLab repository, create a new Pages project, and select “Next.js” from the list of framework presets. This will configure your project to use the @cloudflare/next-on-pages CLI which builds and transforms your project into something we can deploy on Pages. Navigate to the project settings and add an environment variable, NODE_VERSION set to 14 or greater, as well as the following compatibility flags: streams_enable_constructors and transformstream_enable_standard_constructor. You should now be able to deploy your Next.js application. If you want to read more, you can find a detailed guide in our documentation.
How it runs on Cloudflare Pages
Compatibility Dates and Compatibility Flags
Cloudflare Workers has solved the versioning problem by introducing compatibility dates and compatibility flags. While it has been in beta, Pages Functions has always defaulted to using the oldest version of the Workers runtime. We’ve now introduced controls to allow developers to set these dates and flags on their Pages projects environments.
By keeping this date recent, you are able to opt in to the latest features and bug fixes that the Cloudflare Workers runtime offers, but equally, you’re completely free to keep the date on whatever works for you today, and we’ll continue to support the functionality at that point in time, forever. We also allow you to set these dates for your production and preview environments independently which will let you test these changes out safely in a preview deployment before rolling it out in production.
We’ve been working on adding more support for the Streams API to the Workers Runtime, and some of this functionality is gated behind the flags we added to the project earlier. These flags are currently scheduled to graduate and become on-by-default on a future compatibility date, 2022-11-30.
The @cloudflare/next-on-pages CLI
Vercel introduced the Build Output API in July 2022 as a “zero configuration” directory structure which the Vercel platform inherently understands and can deploy. We’ve decided to hook into this same API as a way to build Next.js projects consistently that we can understand and deploy.
The open-source @cloudflare/next-on-pages CLI runs npx vercel build behind the scenes, which produces a .vercel/output directory. This directory conforms to the Build Output API, and of particular interest, contains a config.json, static folder and folder of functions. The @cloudflare/next-on-pages CLI then parses this config.json manifest, and combines all the functions into a single Pages Functions ‘advanced mode’ _worker.js.
At this point, the build is finished. Pages then automatically picks up this _worker.js and deploys it with Pages Functions atop the static directory.
Although currently just an implementation detail, we opted to use this Build Output API for a number of reasons. We’re also exploring other similar functionality natively on the Pages platform. We already have one “magical” directory, the functions directory which we use for the file-based routing of Pages Functions. It’s possible that we offer other fixed directory structures which would reduce the need for configuration of any projects using frameworks which adopt the API. Let us know in Discord if you have any thoughts or preferences on what you would like to see!
Additionally, if more full-stack frameworks do adopt Vercel’s Build Output API, we may have automatic support for them running on Pages with this CLI. We’ve only been experimenting with Next.js here so far (and SvelteKit, Remix and Qwik all have their own way of building their projects on Pages at the moment), but it’s possible that in the future we may converge on a standard approach which could be shared between frameworks and platforms. We’re excited to see how this might transpire. Again, let us know if you have thoughts!
Experimental webpack minification
As part of the compilation from .vercel/output/functions to an _worker.js, the @cloudflare/next-on-pages CLI can perform an experimental minification to give you more space for your application to run on Workers. Right now, most accounts are limited to a maximum script size of 1MB (although this can be raised in some circumstances—get in touch!). You can ordinarily fit quite a lot of code in this, but one thing notable about Next.js’ build process at the moment is that it creates webpack-compiled, fully-formed and fully-isolated functions scripts in each of the directories in .vercel/output/functions. This means that each function ends up looking something like this:
The script contains everything that’s needed to deploy this function, and most of the logic exists in these webpack chunks, but that means that each function has a lot of code shared with its siblings. Quickly, you’ll reach the 1MB limit, if you naively deployed all these functions together.
Our @cloudflare/next-on-pages --experimental-minify CLI argument deals with this problem by analyzing webpack chunks which are re-used in multiple places in this .vercel/output/functions directory and extracts out that code to a common place. This allows our compiler (esbuild) to efficiently combine this code, without duplicating it in all of these places. This process is experimental for the time being, while we look to make this as efficient as possible, without introducing any bugs as a result. Please file an issue on GitHub if you notice any difference in behavior when using --experimental-minify.
Finally, we’re also looking at how we can bring Wasm support to Pages Functions which will unlock ever more use-cases for your full-stack applications. Stay tuned for more information on how we’ll be offering this soon.
Try creating a Next.js Edge Runtime application and deploying it to Cloudflare Pages with the example above or by following the guide in our documentation. Let us know if you have any questions or face any issues in Discord or on GitHub, and please report any quirks of the --experimental-minify argument. As always, we’re excited to see what you build!
To help developers build better web applications we researched and devised a fragments architecture to build micro-frontends using Cloudflare Workers that is lightning fast, cost-effective to develop and operate, and scales to the needs of the largest enterprise teams without compromising release velocity or user experience.
Here we share a technical overview and a proof of concept of this architecture.
Why micro-frontends?
One of the challenges of modern frontend web development is that applications are getting bigger and more complex. This is especially true for enterprise web applications supporting e-commerce, banking, insurance, travel, and other industries, where a unified user interface provides access to a large amount of functionality. In such projects it is common for many teams to collaborate to build a single web application. These monolithic web applications, usually built with JavaScript technologies like React, Angular, or Vue, span thousands, or even millions of lines of code.
When a monolithic JavaScript architecture is used with applications of this scale, the result is a slow and fragile user experience with low Lighthouse scores. Furthermore, collaborating development teams often struggle to maintain and evolve their parts of the application, as their fates are tied with fates of all the other teams, so the mistakes and tech debt of one team often impacts all.
Drawing on ideas from microservices, the frontend community has started to advocate for micro-frontends to enable teams to develop and deploy their features independently of other teams. Each micro-frontend is a self-contained mini-application, that can be developed and released independently, and is responsible for rendering a “fragment” of the page. The application then combines these fragments together so that from the user’s perspective it feels like a single application.
An application consisting of multiple micro-frontends
Fragments could represent vertical application features, like “account management” or “checkout”, or horizontal features, like “header” or “navigation bar”.
Client-side micro-frontends
A common approach to micro-frontends is to rely upon client-side code to lazy load and stitch fragments together (e.g. via Module Federation). Client-side micro-frontend applications suffer from a number of problems.
Common code must either be duplicated or published as a shared library. Shared libraries are problematic themselves. It is not possible to tree-shake unused library code at build time resulting in more code than necessary being downloaded to the browser and coordinating between teams when shared libraries need to be updated can be complex and awkward.
Also, the top-level container application must bootstrap before the micro-frontends can even be requested, and they also need to boot before they become interactive. If they are nested, then you may end up getting a waterfall of requests to get micro-frontends leading to further runtime delays.
These problems can result in a sluggish application startup experience for the user.
Server-side rendering could be used with client-side micro-frontends to improve how quickly a browser displays the application but implementing this can significantly increase the complexity of development, deployment and operation. Furthermore, most server-side rendering approaches still suffer from a hydration delay before the user can fully interact with the application.
Addressing these challenges was the main motivation for exploring an alternative solution, which relies on the distributed, low latency properties provided by Cloudflare Workers.
Micro-frontends on Cloudflare Workers
Cloudflare Workers is a compute platform that offers a highly scalable, low latency JavaScript execution environment that is available in over 275 locations around the globe. In our exploration we used Cloudflare Workers to host and render micro-frontends from anywhere on our global network.
Fragments architecture
In this architecture the application consists of a tree of “fragments” each deployed to Cloudflare Workers that collaborate to server-side render the overall response. The browser makes a request to a “root fragment”, which will communicate with “child fragments” to generate the final response. Since Cloudflare Workers can communicate with each other with almost no overhead, applications can be server-side rendered quickly by child fragments, all working in parallel to render their own HTML, streaming their results to the parent fragment, which combines them into the final response stream delivered to the browser.
The demo application is a simple filtered gallery of cloud images built using our fragments architecture. Try selecting a tag in the type-ahead to filter the images listed in the gallery. Then change the delay on the stream of cloud images to see how the type-ahead filtering can be interactive before the page finishes loading.
Multiple Cloudflare Workers
The application is composed of a tree of six collaborating but independently deployable Cloudflare Workers, each rendering their own fragment of the screen and providing their own client-side logic, and assets such as CSS stylesheets and images.
Architectural overview of the Cloud Gallery app
The “main” fragment acts as the root of the application. The “header” fragment has a slider to configure an artificial delay to the display of gallery images. The “body” fragment contains the “filter” fragment and “gallery” fragments. Finally, the “footer” fragment just shows some static content.
The full source code of the demo app is available on GitHub.
Benefits and features
This architecture of multiple collaborating server-side rendered fragments, deployed to Cloudflare Workers has some interesting features.
Encapsulation
Fragments are entirely encapsulated, so they can control what they own and what they make available to other fragments.
Fragments can be developed and deployed independently
Updating one of the fragments is as simple as redeploying that fragment. The next request to the main application will use the new fragment. Also, fragments can host their own assets (client-side JavaScript, images, etc.), which are streamed through their parent fragment to the browser.
Server-only code is not sent to the browser
As well as reducing the cost of downloading unnecessary code to the browser, security sensitive code that is only needed for server-side rendering the fragment is never exposed to other fragments and is not downloaded to the browser. Also, features can be safely hidden behind feature flags in a fragment, allowing more flexibility with rolling out new behavior safely.
Composability
Fragments are fully composable – any fragment can contain other fragments. The resulting tree structure gives you more flexibility in how you architect and deploy your application. This helps larger projects to scale their development and deployment. Also, fine-grain control over how fragments are composed, could allow fragments that are expensive to server-side render to be cached individually.
Fantastic Lighthouse scores
Streaming server-rendered HTML results in great user experiences and Lighthouse scores, which in practice means happier users and higher chance of conversions for your business.
Lighthouse scores for the Cloud Gallery app
Each fragment can parallelize requests to its child fragments and pipe the resulting HTML streams into its own single streamed server-side rendered response. Not only can this reduce the time to render the whole page but streaming each fragment through to the browser reduces the time to the first byte of each fragment.
Eager interactivity
One of the powers of a fragments architecture is that fragments can become interactive even while the rest of the application (including other fragments) is still being streamed down to the browser.
In our demo, the “filter” fragment is immediately interactive as soon as it is rendered, even if the image HTML for the “gallery” fragment is still loading.
To make it easier to see this, we added a slider to the top of the “header” that can simulate a network or database delay that slows down the HTML stream which renders the “gallery” images. Even when the “gallery” fragment is still loading, the type-ahead input, in the “filter” fragment, is already fully interactive.
Just think of all the frustration that this eager interactivity could avoid for web application users with unreliable Internet connection.
Under the hood
As discussed already this architecture relies upon deploying this application as many cooperating Cloudflare Workers. Let’s look into some details of how this works in practice.
We experimented with various technologies, and while this approach can be used with many frontend libraries and frameworks, we found the Qwik framework to be a particularly good fit, because of its HTML-first focus and low JavaScript overhead, which avoids any hydration problems.
Implementing a fragment
Each fragment is a server-side rendered Qwik application deployed to its own Cloudflare Worker. This means that you can even browse to these fragments directly. For example, the “header” fragment is deployed to https://cloud-gallery-header.web-experiments.workers.dev/.
A screenshot of the self-hosted “header” fragment
The header fragment is defined as a Header component using Qwik.This component is rendered in a Cloudflare Worker via a fetch() handler:
The renderResponse() function is a helper we wrote that server-side renders the fragment and streams it into the body of a Response that we return from the fetch() handler.
The header fragment serves its own JavaScript and image assets from its Cloudflare Worker. We configure Wrangler to upload these assets to Cloudflare and serve them from our network.
Implementing fragment composition
Fragments that contain child fragments have additional responsibilities:
Request and inject child fragments when rendering their own HTML.
Proxy requests for child fragment assets through to the appropriate fragment.
Injecting child fragments
The position of a child fragment inside its parent can be specified by a FragmentPlaceholder helper component that we have developed. For example, the “body” fragment has the “filter” and “gallery” fragments.
The FragmentPlaceholder component is responsible for making a request for the fragment and piping the fragment stream into the output stream.
Proxying asset requests
As mentioned earlier, fragments can host their own assets, especially client-side JavaScript files. When a request for an asset arrives at the parent fragment, it needs to know which child fragment should receive the request.
In our demo we use a convention that such asset paths will be prefixed with /_fragment/<fragment-name>. For example, the header logo image path is /_fragment/header/cf-logo.png. We developed a tryGetFragmentAsset() helper which can be added to the parent fragment’s fetch() handler to deal with this:
If a fragment hosts its own assets, then we need to ensure that any HTML it renders uses the special _fragment/<fragment-name> path prefix mentioned above when referring to these assets. We have implemented a strategy for this in the helpers we developed.
The FragmentPlaceholder component adds a base searchParam to the fragment request to tell it what this prefix should be. The renderResponse() helper extracts this prefix and provides it to the Qwik server-side renderer. This ensures that any request for client-side JavaScript has the correct prefix. Fragments can apply a hook that we developed called useFragmentRoot(). This allows components to gather the prefix from a FragmentContext context.
For example, since the “header” fragment hosts the Cloudflare and GitHub logos as assets, it must call the useFragmentRoot() hook:
Cloudflare Workers provide a mechanism called service bindings to make requests between Cloudflare Workers efficiently that avoids network requests. In the demo we use this mechanism to make the requests from parent fragments to their child fragments with almost no performance overhead, while still allowing the fragments to be independently deployed.
Comparison to current solutions
This fragments architecture has three properties that distinguish it from other current solutions.
Unlike monoliths, or client-side micro-frontends, fragments are developed and deployed as independent server-side rendered applications that are composed together on the server-side. This significantly improves rendering speed, and lowers interaction latency in the browser.
Unlike server-side rendered micro-frontends with Node.js or cloud functions, Cloudflare Workers is a globally distributed compute platform with a region-less deployment model. It has incredibly low latency, and a near-zero communication overhead between fragments.
Unlike solutions based on module federation, a fragment’s client-side JavaScript is very specific to the fragment it is supporting. This means that it is small enough that we don’t need to have shared library code, eliminating the version skew issues and coordination problems when updating shared libraries.
Future possibilities
This demo is just a proof of concept, so there are still areas to investigate. Here are some of the features we’d like to explore in the future.
Caching
Each micro-frontend fragment can be cached independently of the others based on how static its content is. When requesting the full page, the fragments only need to run server-side rendering for micro-frontends that have changed.
An application where the output of some fragments are cached
With per-fragment caching you can return the HTML response to the browser faster, and avoid incurring compute costs in re-rendering content unnecessarily.
Fragment routing and client-side navigation
Our demo application used micro-frontend fragments to compose a single page. We could however use this approach to implement page routing as well. When server-side rendering, the main fragment could insert the appropriate “page” fragment based on the visited URL. When navigating, client-side, within the app, the main fragment would remain the same while the displayed “page” fragment would change.
An application where each route is delegated to a different fragment
This approach combines the best of server-side and client-side routing with the power of fragments.
Using other frontend frameworks
Although the Cloud Gallery application uses Qwik to implement all fragments, it is possible to use other frameworks as well. If really necessary, it’s even possible to mix and match frameworks.
To achieve good results, the framework of choice should be capable of server-side rendering, and should have a small client-side JavaScript footprint. HTML streaming capabilities, while not required, can significantly improve performance of large applications.
An application using different frontend frameworks
Incremental migration strategies
Adopting a new architecture, compute platform, and deployment model is a lot to take in all at once, and for existing large applications is prohibitively risky and expensive. To make this fragment-based architecture available to legacy projects, an incremental adoption strategy is a key.
Developers could test the waters by migrating just a single piece of the user-interface within their legacy application to a fragment, integrating with minimal changes to the legacy application. Over time, more of the application could then be moved over, one fragment at a time.
Convention over configuration
As you can see in the Cloud Gallery demo application, setting up a fragment-based micro-frontend requires quite a bit of configuration. A lot of this configuration is very mechanical and could be abstracted away via conventions and better tooling. Following productivity-focused precedence found in Ruby on Rails, and filesystem based routing meta-frameworks, we could make a lot of this configuration disappear.
Try it yourself!
There is still so much to dig into! Web applications have come a long way in recent years and their growth is hard to overstate. Traditional implementations of micro-frontends have had only mixed success in helping developers scale development and deployment of large applications. Cloudflare Workers, however, unlock new possibilities which can help us tackle many of the existing challenges and help us build better web applications.
If all of these sounds interesting to you, and you would like to work with us on improving the developer experience for Cloudflare Workers, we are also happy to share that we are hiring!
From our earliest days, Cloudflare has stood for helping build a better Internet that’s accessible to all. It’s core to our mission that anyone who wants to start building on the Internet should be able to do so easily, and without the barriers of prohibitively expensive or difficult to use infrastructure.
Nowhere is this philosophy more important – and more impactful to the Internet – than with our developer platform, Cloudflare Workers. Workers is, quite simply, where developers and entrepreneurs start on Day 1. It’s a full developer platform that includes cloud storage; website hosting; SQL databases; and of course, the industry’s leading serverless product. The platform’s ease-of-use and accessible pricing (all the way down to free) are critical in advancing our mission. For startups, this translates into fast, easy deployment and iteration, that scales seamlessly with predictable, transparent and cost-effective pricing. Building a great business from scratch is hard enough – we ought to know! – and so we’re aiming to take all the complexity out of your application infrastructure.
Announcing the Workers Launchpad funding program
Today, we’re taking things a step further and making it easier for startups to build the business of their dreams. We’re announcing a $1.25 billion Workers Launchpad funding program in partnership with some of the world’s leading venture capital firms. Any startup built on Workers can apply. As is the case with the Workers Platform itself, we’ve tried to make applying dead simple: it should take you less than five minutes to submit your application through the Workers Launchpad portal.
How does it work? The only requirement for being eligible for the funding program is that you’ve built your core infrastructure on Workers. If you’re new to Cloudflare and Cloudflare Workers, check out our Startup Plan to get started. We hope these resources will be helpful to all startups and help level the playing field, no matter where in the world you might be.
Once you submit your application, it will be reviewed by our Launchpad team, several of whom are former entrepreneurs and venture capital folks themselves. They’ll match promising applicants with our VC partners who have the most expertise in your space (more on them below). Every quarter, we’ll announce the winners of our Launchpad program. Winners, our “Workers Founders”, will be guaranteed the opportunity to pitch the VC partner(s) that we’ve determined would be a good match for your business. It’s a win-win all around. VCs get the opportunity to invest in businesses they know are being built on a forward-looking, world-class, development platform. Entrepreneurs get connected to world-class VCs. And for the first class of winners, we’ll have a few added perks that we describe in more detail below.
Who are the VCs that you might get a chance to pitch to?
When we approached our friends in the venture community with our vision for the Workers Launchpad, we received incredibly positive feedback and excitement. Many have seen firsthand the competitive advantages of building on Workers through their own portfolio companies. Moreover, Cloudflare is home to one of the largest developer communities on Earth with approximately 20% of the world’s websites on our network. As such, we can play a unique role in matching great entrepreneurs with great VCs to further not only the Workers platform, but also the Internet ecosystem, for everyone.
We’re honored to announce a world-class group of VC Launch Partners supporting this program and the ecosystem of Workers-based startups:
More on why we’re doing this
So why are we doing this? The simple answer is we’re proud of our Workers Developer Platform and think that everyone should be using it. Entrepreneurs who develop on Workers can ship faster; more easily and cost-effectively; and in a way that future proofs your infrastructure:
Speed. Development velocity isn’t just a convenience for an entrepreneur. It’s a massive competitive advantage. In fact, development velocity is one of Cloudflare’s competitive advantages – we’re able to develop quickly because we build on Workers. When you develop on Workers, you don’t need to spend time configuring DNS records, maintaining certificates, scaling up clusters, or building complex deployment pipelines. Focus on developing your application, and Cloudflare will handle the rest.
Ease of use. Startup teams and founders are some of the busiest people on earth. You shouldn’t have to think about – or make complicated decisions about – IT infrastructure. Questions like: “Which availability zone should I choose?”, or “Will I be able to scale up my infrastructure in time for our next viral marketing campaign?” shouldn’t have to cross your mind! And on the Workers Platform, they don’t. The code you and your team writes automatically deploys quickly and consistently across Cloudflare’s global network in 275+ cities in over 100 countries. Cloudflare securely and scalably connects your users to your applications, regardless of where those applications are hosted or how many users suddenly sign up for your product. Developers can easily manage globally distributed applications with a programmable network that easily connects to whatever services they need to talk to.
Future-proofing your infrastructure and your wallet. Cloudflare’s massive global network – that’s distributed across 275+ cities in over 100 countries – is able to scale with your business, no matter how large it grows to become. We also help you remain compliant with local laws and regulations as you expand around the world, with capabilities like Workers’ Jurisdictional Restrictions for Durable Objects. You can sleep soundly at night instead of worrying about how to level up your infrastructure in the midst of shifting regulations, and equally importantly, knowing that you will not wake up to any surprise bills. Many of us have had the experience of being charged unexpected and / or exorbitant fees from our cloud providers. For example, providers will often make it easy and free to onboard your application or data, but charge exorbitant rates when you want to move them out (i.e. egress fees). Cloudflare will never charge for egress. Our pricing is simple, and we constantly aim to be the low-cost provider, no matter how large your business grows to be.
Dogfooding our own product
We’re excited about Workers not only because we’ve built our own infrastructure on it, but also because we’re seeing the incredible things others have built on it. In fact, we acquired a company built entirely on Workers at the end of last year, an Isareli start-up named Zaraz, which secures and accelerates third party web tools. Workers allowed Zaraz to replace the multiple network requests of each tool running on a website with one single request, effectively streamlining a messy web of extensions into a single lightweight application. This acquisition opened our eyes to the power of the global community that’s built on our platform, and left us motivated to help startups built on Workers find the funding, mentorship, and support needed to grow.
But wait, there’s more!
To make it even easier for startups to take advantage of all the benefits that Workers has to offer, applicants to the Workers Launchpad program who have raised less than $3 million in total external funding will automatically have the option to receive Cloudflare’s Startup Plan. This plan includes all the elements of Cloudflare’s Pro and Business Plans ($2,400 annual value) plus higher tiers of our Stream video product, our Teams Zero Trust security suite and the Workers platform. To make sure the full range of our developer platform is accessible to startups, we recently more than tripled the number of products available in this plan, which now includes email security, R2, Pages, KV, and many others.
Furthermore, all startups that apply by October 31, 2022, will be eligible to be selected for the Winter 2022 class of Workers Founders, which will unlock additional support, mentorship, and marketing opportunities. Being selected as a Workers Founder will get you a chance to practice your pitch with investors, engage with leaders from Cloudflare, and get advice on how to build a successful business from topics like recruiting to marketing, sales, and beyond during a virtual Workers Founders Bootcamp Week. The program will culminate in a virtual Demo Day, so you can show the world what you’ve been building. We’re leaning in to help promising entrepreneurs join us in our mission to help build a better Internet.
Helping make the Internet better for all
Accessibility and ease of use are core to everything we do at Cloudflare. We will always make our products and platforms so easy to use that even the smallest business or hobbyist can easily use them. We hope the Workers Launchpad funding program encourages entrepreneurs from all around the world, and from all backgrounds, to start building on Workers, and makes it easier for you to find the funding you need to build the business of your dreams.
Cloudflare is not providing any funding or making any funding decisions, and there is no guarantee that any particular company will receive funding through the program. All funding decisions will be made by the venture capital firms that participate in the program. Cloudflare is not a registered broker-dealer, investment adviser, or other similar intermediary.
Today I’m proud to introduce the first beta release of workerd, the JavaScript/Wasm runtime based on the same code that powers Cloudflare Workers. workerd is Open Source under the Apache License version 2.0.
workerd shares most of its code with the runtime that powers Cloudflare Workers, but with some changes designed to make it more portable to other environments. The name “workerd” (pronounced “worker dee”) comes from the Unix tradition of naming servers with a “-d” suffix standing for “daemon”. The name is not capitalized because it is a program name, which are traditionally lower-case in Unix-like environments.
What it’s for
Self-hosting Workers
workerd can be used to self-host applications that you’d otherwise run on Cloudflare Workers. It is intended to be a production-ready web server for this purpose. workerd has been designed to be unopinionated about hosting environments, so that it should fit nicely into whatever server/VM/container hosting and orchestration system you prefer. It’s just a web server.
Workers has always been based on standardized APIs, so that code is not locked into Cloudflare, and we work closely with other runtimes to promote compatibility. workerd provides another option to ensure that applications built on Workers can run anywhere, by leveraging the same underlying code to get exact, “bug-for-bug” compatibility.
Local development and testing
workerd is also designed to facilitate realistic local testing of Workers. Up until now, this has been achieved using Miniflare, which simulated the Workers API within a Node.js environment. Miniflare has worked well, but in a number of cases its behavior did not exactly match Workers running on Cloudflare. With the release of workerd, Miniflare and the Wrangler CLI tool will now be able to provide a more accurate simulation by leveraging the same runtime code we use in production.
Programmable proxies
workerd can act as an application host, a proxy, or both. It supports both forward and reverse proxy modes. In all cases, JavaScript code can be used to intercept and process requests and responses before forwarding them on. Traditional web servers and proxies have used bespoke configuration languages with quirks that are hard to master. Programming proxies in JavaScript instead provides more power while making the configuration easier to write and understand.
What it is
workerd is not just another way to run JavaScript and Wasm. Our runtime is uniquely designed in a number of ways.
Server-first
Many non-browser JavaScript and Wasm runtimes are designed to be general-purpose: you can use them to build command-line apps, local GUI apps, servers, or anything in between. workerd is not. It specifically focuses on servers, in particular (for now, at least) HTTP servers.
This means in particular that workerd-based applications are event-driven at the top level. Applications do not open listen sockets and accept connections from them; instead, the runtime pushes events to the application. It may seem like a minor difference, but this basic change in perspective directly enables many of the features below.
Web standard APIs
Wherever possible, Workers (and workerd in particular) offers the same standard APIs found in web browsers, such as Fetch, URL, WebCrypto, and others. This means that code built on workerd is more likely to be portable to browsers as well as to other standards-based runtimes. When Workers launched five years ago, it was unusual for a non-browser to offer web APIs, but we are pleased to see that the broader JavaScript ecosystem is now converging on them.
Nanoservices
workerd is a nanoservice runtime. What does that mean?
Microservices have become popular over the last decade as a way to split monolithic servers into smaller components that could be maintained and deployed independently. For example, a company that offers several web applications with a common user authentication flow might have a separate team that maintains the authentication logic. In a monolithic model, the authentication logic might have been offered to the application teams as a library. However, this could be frustrating for the maintainers of that logic, as making any change might require waiting for every application team to deploy an update to their respective server. By splitting the authentication logic into a separate server that all the others talk to, the authentication team is able to deploy changes on their own schedule.
However, microservices have a cost. What was previously a fast library call instead now requires communicating over a network. In addition to added overhead, this communication requires configuration and administration to ensure security and reliability. These costs become greater as the codebase is split into more and more services. Eventually, the costs outweigh the benefits.
Nanoservices are a new model that achieve the benefits of independent deployment with overhead closer to that of library calls. With workerd, many Workers can be configured to run in the same process. Each Worker runs in a separate “isolate”, which gives the appearance of running independently of the others: each isolate loads separate code and has its own global scope. However, when one Worker explicitly sends a request to another Worker, the destination Worker actually runs in the same thread with zero latency. So, it performs more like a function call.
With nanoservices, teams can now break their code into many more independently-deployed pieces without worrying about the overhead.
(Some in the industry prefer to call nanoservices “functions”, implying that each individual function making up an application could be its own service. I feel, however, that this puts too much emphasis on syntax rather than logical functionality. That said, it is the same concept.)
To really make nanoservices work well, we had to minimize the baseline overhead of each service. This required designing workerd very differently from most other runtimes, so that common resources could be shared between services as much as possible. First, as mentioned, we run many nanoservices within a single process, to share basic process overhead and minimize context switching costs. A second big architectural difference between workerd and other runtimes is how it handles built-in APIs. Many runtimes implement significant portions of their built-in APIs in JavaScript, which must then be loaded separately into each isolate. workerd does not; all the APIs are implemented in native code, so that all isolates may share the same copy of that code. These design choices would be difficult to retrofit into another runtime, and indeed these needs are exactly why we chose to build a custom runtime for Workers from the start.
Homogeneous deployment
In a typical microservices model, you might deploy different microservices to containers running across a cluster of machines, connected over a local network. You might manually choose how many containers to dedicate to each service, or you might configure some form of auto-scaling based on resource usage.
workerd offers an alternative model: Every machine runs every service.
workerd’s nanoservices are much lighter-weight than typical containers. As a result, it’s entirely reasonable to run a very large number of them – hundreds, maybe thousands – on a single server. This in turn means that you can simply deploy every service to every machine in your fleet.
Homogeneous deployment means that you don’t have to worry about scaling individual services. Instead, you can simply load balance requests across the entire cluster, and scale the cluster as needed. Overall, this can greatly reduce the amount of administration work needed.
Cloudflare itself has used the homogeneous model on our network since the beginning. Every one of Cloudflare’s edge servers runs our entire software stack, so any server can answer any kind of request on its own. We’ve found it works incredibly well. This is why services on Cloudflare – including ones that use Workers – are able to go from no traffic at all to millions of requests per second instantly without trouble.
Capability bindings: cleaner configuration and SSRF safety
workerd takes a different approach to most runtimes – indeed, to most software development platforms – in how an application accesses external resources.
Most development platforms start from assuming that the application can talk to the whole world. It is up to the application to figure out exactly what it wants to talk to, and name it in some global namespace, such as using a URL. So, an application server that wants to talk to the authentication microservice might use code like this:
// Traditional approach without capability bindings.
fetch("https://auth-service.internal-network.example.com/api", {
  method: "POST",
  body: JSON.stringify(authRequest),
  headers: { "Authorization": env.AUTH_SERVICE_TOKEN }
});
In workerd, we do things differently. An application starts out with no ability to talk to the rest of the world, and must be configured with specific capability bindings that provide it access to specific external resources. So, an application which needs to be able to talk to the authentication service would be configured with a binding called authService, and the code would look something like this:
// Capability-based approach. Hostname doesn't matter; all
// requests to AUTH_SERVICE.fetch() go to the auth service.
env.AUTH_SERVICE.fetch("https://auth/api", {
 method: "POST",
 body: JSON.stringify(authRequest),
});
This may at first appear to be a trivial difference. In both cases, we have to use configuration to control access to external services. In the traditional approach, we’d provide access tokens (and probably the service’s hostname) as environment variables. In the new approach, the environment goes a bit further to provide a full-fledged object. Is this just syntax sugar?
It turns out, this slight change has huge advantages:
First, we can now restrict the global fetch() function to accept only publicly-routable URLs. This makes applications totally immune to SSRF attacks! You cannot trick an application into accessing an internal service unintentionally if the code to access internal services is explicitly different. (In fact, the global fetch() is itself backed by a binding, which can be configured. workerd defaults to connecting it to the public internet, but you can also override it to permit private addresses if you want, or to route to a specific proxy service, or to be blocked entirely.)
With that done, we now have an interesting property: All internal services which an application uses must be configurable. This means:
You can easily see a complete list of the internal services an application talks to, without reading all the code.
You can always replace these services with mocks for testing purposes.
You can always configure an application to authenticate itself differently (e.g. client certificates) or use a different back end, without changing code.
The receiving end of a binding benefits, too. Take the authentication service example, above. The auth service may be another Worker running in workerd as a nanoservice. In this case, the auth service does not need to be bound to any actual network address. Instead, it may be made available strictly to other Workers through their bindings. In this case, the authentication service doesn’t necessarily need to verify that a request received came from an allowed client – because only allowed clients are able to send requests to it in the first place.
Overall, capability bindings allow simpler code that is secure by default, more composable, easier to test, and easier to understand and maintain.
Always backwards compatible
Cloudflare Workers has a hard rule against ever breaking a live Worker running in production. This same dedication to backwards compatibility extends to workerd.
workerd shares Workers’ compatibility date system to manage breaking changes. Every Worker must be configured with a “compatibility date”. The runtime then ensures that the API behaves exactly as it did on that date. At your leisure, you may check the documentation to see if new breaking changes are introduced at a future date, and update your code for them. Most such changes are minor and most code won’t require any changes. However, you are never obliged to update. Old dates will continue to be supported by newer versions of workerd. It is always safe to update workerd itself without updating your code.
What it’s not
To avoid misleading or disappointing anyone, I need to take a moment to call out what workerd is not.
workerd is not a Secure Sandbox
It’s important to note that workerd is not, on its own, a secure way to run possibly-malicious code. If you wish to run code you don’t trust using workerd, you must enclose it in an additional sandboxing layer, such as a virtual machine configured for sandboxing.
workerd itself is designed such that a Worker should not be able to access any external resources to which it hasn’t been granted a capability. However, a complete sandbox solution not only must be designed to restrict access, but also must account for the possibility of bugs – both in software and in hardware. workerd on its own is not sufficient to protect against hardware bugs like Spectre, nor can it adequately defend against the possibility of vulnerabilities in V8 or in workerd’s own code.
The Cloudflare Workers service uses the same code found in workerd, but adds many additional layers of security on top to harden against such bugs. I described some of these in a past blog post. However, these measures are closely tied to our particular environment. For example, we rely on build automation to push V8 patches to production immediately upon becoming available; we separate customers according to risk profile; we rely on non-portable kernel features and assumptions about the host system to enforce security and resource limits. All of this is very specific to our environment, and cannot be packaged up in a reusable way.
workerd is not an independent project
workerd is the core of Cloudflare Workers, a fast-moving project developed by a dedicated team at Cloudflare. We are not throwing code over the wall to forget about, nor are we expecting volunteers to do our jobs for us. workerd’s GitHub repository will be the canonical source used by Cloudflare Workers and our team will be doing much of their work directly in this repository. Just like V8 is developed primarily by the Chrome team for use in Chrome, workerd will be developed primarily by the Cloudflare Workers team for use in Cloudflare Workers.
This means we cannot promise that external contributions will sit on a level playing field with internal ones. Code reviews take time, and work that is needed for Cloudflare Workers will take priority. We also cannot promise we will accept every feature contribution. Even if the code is already written, reviews and maintenance have a cost. Within Cloudflare, we have a product management team who carefully evaluates what features we should and shouldn’t offer, and plenty of ideas generated internally ultimately don’t make the cut.
If you want to contribute a big new feature to workerd, your best bet is to talk to us before you write code, by raising an issue on GitHub early to get input. That way, you can find out if we’re likely to accept a PR before you write it. We also might be able to give hints on how best to implement.
It’s also important to note that while workerd’s internal interfaces may sometimes appear clean and reusable, we cannot make any guarantee that those interfaces won’t completely change on a whim. If you are trying to build on top of workerd internals, you will need to be prepared either to accept a fair amount of churn, or pin to a specific version.
workerd is not an off-the-shelf edge compute platform
As hinted above, the full Cloudflare Workers service involves a lot of technology beyond workerd itself, including additional security, deployment mechanisms, orchestration, and so much more. workerd itself is a portion of our runtime codebase, which is itself a small (albeit critical) piece of the overall Cloudflare Workers service.
We are pleased, though, that this means it is possible for us to release this code under a permissive Open Source license.
Try the Beta
As of this blog post, workerd is in beta. If you want to try it out,
Developers continue to build more complex applications on Cloudflare’s Developer Platform. We started with Workers, which brought compute, then introduced KV, Durable Objects, R2, and soon D1, which enabled persistence. Now, as we enable developers to build larger, more sophisticated, and more reliable applications, it’s time to unlock another foundational building block: messaging.
Thus, we’re excited to announce the private beta of Cloudflare Queues, a global message queuing service that allows applications to reliably send and receive messages using Cloudflare Workers. It offers at-least once message delivery, supports batching of messages, and charges no bandwidth egress fees. Let’s queue up the details.
What is a Queue?
Queues enable developers to send and receive messages with a guarantee of delivery. Think of it like the postal service for the Internet. You give it a message, then it handles all the hard work to ensure the message gets delivered in a timely manner. Unlike the real postal service, where it’s possible for a message to get lost, Queues provide a guarantee that each message is delivered at-least once; no matter what. This lets you focus on your application, rather than worry about the chaos of transactions, retries, and backoffs to prevent data loss.
Queues also allow you to scale your application to process large volumes of data. Imagine a million people send you a package in the mail, at the same time. Instead of a million postal workers suddenly showing up at your front door, you would want them to aggregate your mail into batches, then ask you when you’re ready to receive each batch. This lets you decouple and spread load among services that have different throughput characteristics.
How does it work?
Queues are integrated into the fabric of the Cloudflare Workers runtime, with simple APIs that make it easy to send and receive messages. First, you’ll want to send messages to the Queue. You can do this by defining a Worker, referred to as a “producer,” which has a binding to the Queue.
In the example below, a Worker catches JavaScript exceptions and sends them to a Queue. You might notice that any object can be sent to the Queue, including an error. That’s because messages are encoded using the standard structuredClone() algorithm.
Second, you’ll want to process messages in the Queue. You can do this by defining a Worker, referred to as the “consumer,” which will receive messages from the Queue. To facilitate this, there is a new type of event handler, named “queue,” which receives the messages sent to the consumer.
This Worker is configured to receive messages from the previous example. It appends the stack trace of each Error to a log file, then saves it to an R2 bucket.
export default {
  async queue(batch: MessageBatch<Error>, env: Environment) {
     let logs = "";
     for (const message of batch.messages) {
        logs += message.body.stack;
     }
     await env.ERROR_BUCKET.put(`errors/${Date.now()}.log`, logs);
  }
}
Configuration is also easy. You can change the message batch size, message retries, delivery wait time, and dead-letter queue. Here’s a snippet of the wrangler.toml configuration when deploying with wrangler, our command-line interface
Above are two different wrangler.tomls, one for a producer and another for a consumer. It is also possible for a producer and consumer to be implemented by the same Worker. To see the full list of options and examples, see the documentation.
What can you build with it?
You can use Cloudflare Queues to defer tasks and guarantee they get processed, decouple load among different services, batch events and process them together, and send messages from Worker to Worker.
To demonstrate, we’ve put together a demo application that you can run on your local machine using wrangler. It shows how Queues can batch messages and handle failures in your code, here’s a preview of it in action:
In addition to batching, here are other examples of what you can build with Queues:
Off-load tasks from the critical path of a Workers request.
Guarantee messages get delivered to a service that talks HTTP.
Transform, filter, and fan-out messages to multiple Queues.
Cloudflare Queues gives you the flexibility to decide where to route messages. Instead of static configuration files that define routing keys and patterns, you can use JavaScript to define custom logic for how you filter and fan-out to multiple Queues. In the next example, you can distribute work to different Queues based on the attributes of a user.
export default {
  async queue(batch: MessageBatch, env: Environment) {
    for (const message of batch.messages) {
      const user = message.body;
      if (isEUResident(user)) {
        await env.EU_QUEUE.send(user);
      }
      if (isForgotten(user)) {
        await env.DELETION_QUEUE.send(user);
      }
    }
  }
}
We will also support integrations with Cloudflare products, like R2. For example, you might configure an R2 bucket to send lifecycle events to a Queue or archive messages to a R2 bucket for long-term storage.
How much does it cost?
Cloudflare Queues has a simple, transparent pricing model that’s easy to predict. It costs $0.40 per million operations, which is defined for every 64 KB chunk of data that is written, read, or deleted. There are also no egregious bandwidth fees for data in or out — unlike Amazon’s SQS or Google’s Pub/Sub.
To effectively deliver a message, it usually takes three operations: one write, one read, and one acknowledgement. You can estimate your usage by considering the cost of messages delivered, which is $1.20 per million. (calculated as 3 x \$0.40)
When can I try it?
You can register to join the waitlist as we work towards a beta launch. You’ll have an opportunity to try it out, for free. Once it’s ready, we’ll launch an open beta for everyone to try.
In the meantime, you can read the documentation to view our code samples, see which features will be supported, and learn what you can build. If you’re in our developer Discord, you stay up-to-date by joining the #queues-beta channel. If you’re an Enterprise customer, reach out to your account team to schedule a session with our Product team.
We’re excited to see what you build with Cloudflare Queues. Let the queuing begin!
When we announced D1 in May of this year, we knew it would be the start of something new – our first SQL database with Cloudflare Workers. Prior to D1 we’ve announced storage options like KV (key-value store), Durable Objects (single location, strongly consistent data storage) and R2 (blob storage). But the question always remained “How can I store and query relational data without latency concerns and an easy API?”
The long awaited “Cloudflare Database” was the true missing piece to build your application entirely on Cloudflare’s global network, going from a blank canvas in VSCode to a full stack application in seconds. Compatible with the popular SQLite API, D1 empowers developers to build out their databases without getting bogged down by complexity and having to manage every underlying layer.
Since our launch announcement in May and private beta in June, we’ve made great strides in building out our vision of a serverless database. With D1 still in private beta but an open beta on the horizon, we’re excited to show and tell our journey of building D1 and what’s to come.
The D1 Experience
We knew from Cloudflare Workers feedback that using Wrangler as the mechanism to create and deploy applications is loved and preferred by many. That’s why when Wrangler 2.0 was announced this past May alongside D1, we took advantage of the new and improved CLI for every part of the experience from data creation to every update and iteration. Let’s take a quick look on how to get set up in a few easy steps.
Create your database
With the latest version of Wrangler installed, you can create an initialized empty database with a quick
npx wrangler d1 create my_database_name
To get your database up and running! Now it’s time to add your data.
Bootstrap it
It wouldn’t be the “Cloudflare way” if you had to sit through an agonizingly long process to get set up. So we made it easy and painless to bring your existing data from an old database and bootstrap your new D1 database. You can run
and pass through an existing SQLite .sql file of your choice. Your database is now ready for action.
Develop & Test Locally
With all the improvements we’ve made to Wrangler since version 2 launched a few months ago, we’re pleased to report that D1 has full remote & local wrangler dev support:
When running wrangler dev -–local -–persist, an SQLite file will be created inside .wrangler/state. You can then use a local GUI program for managing it, like SQLiteFlow (https://www.sqliteflow.com/) or Beekeeper (https://www.beekeeperstudio.io/).
Or you can simply use SQLite directly with the SQLite command line by running sqlite3 .wrangler/state/d1/DB.sqlite3:
Automatic backups & one-click restore
No matter how much you test your changes, sometimes things don’t always go according to plan. But with Wrangler you can create a backup of your data, view your list of backups or restore your database from an existing backup. In fact, during the beta, we’re taking backups of your data every hour automatically and storing them in R2, so you will have the option to rollback if needed.
And the best part – if you want to use a production snapshot for local development or to reproduce a bug, simply copy it into the .wrangler/state directory and wrangler dev –-local –-persist will pick it up!
Let’s download a D1 backup to our local disk. It’s SQLite compatible.
Now let’s run our D1 worker locally, from the backup.
Create and Manage from the dashboard
However, we realize that CLIs are not everyone’s jam. In fact, we believe databases should be accessible to every kind of developer – even those without much database experience! D1 is available right from the Cloudflare dashboard giving you near total command parity with Wrangler in just a few clicks. Bootstrapping your database, creating tables, updating your database, viewing tables and triggering backups are all accessible right at your fingertips.
Changes made in the UI are instantly available to your Worker — no deploy required!
We’ve told you about some of the improvements we’ve landed since we first announced D1, but as always, we also wanted to give you a small taste (with some technical details) of what’s ahead. One really important functionality of a database is transactions — something D1 wouldn’t be complete without.
Sneak peek: how we’re bringing JavaScript transactions to D1
With D1, we strive to present a dramatically simplified interface to creating and querying relational data, which for the most part is a good thing. But simplification occasionally introduces drawbacks, where a use-case is no longer easily supported without introducing some new concepts. D1 transactions are one example.
Transactions are a unique challenge
You don’t need to specify where a Cloudflare Worker or a D1 database run—they simply run everywhere they need to. For Workers, that is as close as possible to the users that are hitting your site right this second. For D1 today, we don’t try to run a copy in every location worldwide, but dynamically manage the number and location of read-only replicas based on how many queries your database is getting, and from where. However, for queries that make changes to a database (which we generally call “writes” for short), they all have to travel back to the single Primary D1 instance to do their work, to ensure consistency.
But what if you need to do a series of updates at once? While you can send multiple SQL queries with .batch() (which does in fact use database transactions under the hood), it’s likely that, at some point, you’ll want to interleave database queries & JS code in a single unit of work.
This is exactly what database transactions were invented for, but if you try running BEGIN TRANSACTION in D1 you’ll get an error. Let’s talk about why that is.
Why native transactions don’t work The problem arises from SQL statements and JavaScript code running in dramatically different places—your SQL executes inside your D1 database (primary for writes, nearest replica for reads), but your Worker is running near the user, which might be on the other side of the world. And because D1 is built on SQLite, only one write transaction can be open at once. Meaning that, if we permitted BEGIN TRANSACTION, any one Worker request, anywhere in the world, could effectively block your whole database! This is a quite dangerous thing to allow:
A Worker could start a transaction then crash due to a software bug, without calling ROLLBACK. The primary would be blocked, waiting for more commands from a Worker that would never come (until, probably, some timeout).
Even without bugs or crashes, transactions that require multiple round-trips between JavaScript and SQL could end up blocking your whole system for multiple seconds, dramatically limiting how high an application built with Workers & D1 could scale.
But allowing a developer to define transactions that mix both SQL and JavaScript makes building applications with Workers & D1 so much more flexible and powerful. We need a new solution (or, in our case, a new version of an old solution).
A way forward: stored procedures Stored procedures are snippets of code that are uploaded to the database, to be executed directly next to the data. Which, at first blush, sounds exactly like what we want.
However, in practice, stored procedures in traditional databases are notoriously frustrating to work with, as anyone who’s developed a system making heavy use of them will tell you:
They’re often written in a different language to the rest of your application. They’re usually written in (a specific dialect of) SQL or an embedded language like Tcl/Perl/Python. And while it’s technically possible to write them in JavaScript (using an embedded V8 engine), they run in such a different environment to your application code it still requires significant context-switching to maintain them.
Having both application code and in-database code affects every part of the development lifecycle, from authoring, testing, deployment, rollbacks and debugging. But because stored procedures are usually introduced to solve a specific problem, not as a general purpose application layer, they’re often managed completely manually. You can end up with them being written once, added to the database, then never changed for fear of breaking something.
With D1, we can do better.
The point of a stored procedure was to execute directly next to the data—uploading the code and executing it inside the database was simply a means to that end. But we’re using Workers, a global JavaScript execution platform, can we use them to solve this problem?
It turns out, absolutely! But here we have a few options of exactly how to make it work, and we’re working with our private beta users to find the right API. In this section, I’d like to share with you our current leading proposal, and invite you all to give us your feedback.
When you connect a Worker project to a D1 database, you add the section like the following to your wrangler.toml:
[[ d1_databases ]]
# What binding name to use (e.g. env.DB):
binding = "DB"
# The name of the DB (used for wrangler d1 commands):
database_name = "my-d1-database"
# The D1's ID for deployment:
database_id = "48a4224e-...3b09"
# Which D1 to use for `wrangler dev`:
# (can be the same as the previous line)
preview_database_id = "48a4224e-...3b09"

# NEW: adding "procedures", pointing to a new JS file:
procedures = "./src/db/procedures.js"
That D1 Procedures file would contain the following (note the new db.transaction() API, that is only available within a file like this):
export default class Procedures {
  constructor(db, env, ctx) {
    this.db = db
  }

  // any methods you define here are available on env.DB.Procedures
  // inside your Worker
  async Checkout(cartId: number) {
    // Inside a Procedure, we have a new db.transaction() API
    const result = await this.db.transaction(async (txn) => {

      // Transaction has begun: we know the user can't add anything to
      // their cart while these actions are in progress.
      const [cart, user] = Helpers.loadCartAndUser(cartId)

      // We can update the DB first, knowing that if any of the later steps
      // fail, all these changes will be undone.
      await this.db
        .prepare(`UPDATE cart SET status = ?1 WHERE cart_id = ?2`)
        .bind('purchased', cartId)
        .run()
      const newBalance = user.balance - cart.total_cost
      await this.db
        .prepare(`UPDATE user SET balance = ?1 WHERE user_id = ?2`)
        // Note: the DB may have a CHECK to guarantee 'user.balance' can not
        // be negative. In that case, this statement may fail, an exception
        // will be thrown, and the transaction will be rolled back.
        .bind(newBalance, cart.user_id)
        .run()

      // Once all the DB changes have been applied, attempt the payment:
      const { ok, details } = await PaymentAPI.processPayment(
        user.payment_method_id,
        cart.total_cost
      )
      if (!ok) {
        // If we throw an Exception, the transaction will be rolled back
        // and result.error will be populated:
        // throw new PaymentFailedError(details)

        // Alternatively, we can do both of those steps explicitly
        await txn.rollback()
        // The transaction is rolled back, our DB is now as it was when we
        // started. We can either move on and try something new, or just exit.
        return { error: new PaymentFailedError(details) }
      }

      // This is implicitly called when the .transaction() block finishes,
      // but you can explicitly call it too (potentially committing multiple
      // times in a single db.transaction() block).
      await txn.commit()

      // Anything we return here will be returned by the
      // db.transaction() block
      return {
        amount_charged: cart.total_cost,
        remaining_balance: newBalance,
      }
    })

    if (result.error) {
      // Our db.transaction block returned an error or threw an exception.
    }

    // We're still in the Procedure, but the Transaction is complete and
    // the DB is available for other writes. We can either do more work
    // here (start another transaction?) or return a response to our Worker.
    return result
  }
}
And in your Worker, your DB binding now has a “Procedures” property with your function names available:
const { error, amount_charged, remaining_balance } =
  await env.DB.Procedures.Checkout(params.cartId)

if (error) {
  // Something went wrong, `error` has details
} else {
  // Display `amount_charged` and `remaining_balance` to the user.
}
Multiple Procedures can be triggered at one time, but only one db.transaction() function can be active at once: any other write queries or other transaction blocks will be queued, but all read queries will continue to hit local replicas and run as normal. This API gives you the ability to ensure consistency when it’s essential but with the minimal impact on total overall performance worldwide.
Request for feedback
As with all our products, feedback from our users drives the roadmap and development. While the D1 API is in beta testing today, we’re still seeking feedback on the specifics. However, we’re pleased that it solves both the problems with transactions that are specific to D1 and the problems with stored procedures described earlier:
Code is executing as close as possible to the database, removing network latency while a transaction is open.
Any exceptions or cancellations of a transaction cause an instant rollback—there is no way to accidentally leave one open and block the whole D1 instance.
The code is in the same language as the rest of your Worker code, in the exact same dialect (e.g. same TypeScript config as it’s part of the same build).
It’s deployed seamlessly as part of your Worker. If two Workers bind to the same D1 instance but define different procedures, they’ll only see their own code. If you want to share code between projects or databases, extract a library as you would with any other shared code.
In local development and test, the procedure works just like it does in production, but without the network call, allowing seamless testing and debugging as if it was a local function.
Because procedures and the Worker that define them are treated as a single unit, rolling back to an earlier version never causes a skew between the code in the database and the code in the Worker.
The D1 ecosystem: contributions from the community
We’ve told you about what we’ve been up to and what’s ahead, but one of the unique things about this project is all the contributions from our users. One of our favorite parts of private betas is not only getting feedback and feature requests, but also seeing what ideas and projects come to fruition. While sometimes this means personal projects, with D1, we’re seeing some incredible contributions to the D1 ecosystem. Needless to say, the work on D1 hasn’t just been coming from within the D1 team, but also from the wider community and other developers at Cloudflare. Users have been showing off their D1 additions within our Discord private beta channel and giving others the opportunity to use them as well. We wanted to take a moment to highlight them.
workers-qb
Dealing with raw SQL syntax is powerful (and using the D1 .bind() API, safe against SQL injections) but it can be a little clumsy. On the other hand, most existing query builders assume direct access to the underlying DB, and so aren’t suitable to use with D1. So Cloudflare developer Gabriel Massadas designed a small, zero-dependency query builder called workers-qb:
While you can interact with D1 through both Wrangler and the dashboard, Cloudflare Community champion, Isaac McFadyen created the very first D1 console where you can quickly execute a series of queries right through your terminal. With the D1 console, you don’t need to spend time writing the various Wrangler commands we’ve created – just execute your queries.
This includes all bells and whistles you would expect from a modern database console including multiline input, command history, validation for things D1 may not yet support, and ability to save your Cloudflare credentials for later use.
Check out the full project on GitHub or NPM for more information.
Miniflare test Integration
The Miniflare project, which powers Wrangler’s local development experience, also provides fully-fledged test environments for popular JavaScript test runners, Jest and Vitest. With this comes the concept of Isolated Storage, allowing each test to run independently, so that changes made in one don’t affect the others. Brendan Coll, creator of Miniflare, guided the D1 test implementation to give the same benefits:
import Worker from ‘../src/index.ts’
const { DB } = getMiniflareBindings();

beforeAll(async () => {
  // Your D1 starts completely empty, so first you must create tables
  // or restore from a schema.sql file.
  await DB.exec(`CREATE TABLE entries (id INTEGER PRIMARY KEY, value TEXT)`);
});

// Each describe block & each test gets its own view of the data.
describe(‘with an empty DB’, () => {
  it(‘should report 0 entries’, async () => {
    await Worker.fetch(...)
  })
  it(‘should allow new entries’, async () => {
    await Worker.fetch(...)
  })
])

// Use beforeAll & beforeEach inside describe blocks to set up particular DB states for a set of tests
describe(‘with two entries in the DB’, () => {
  beforeEach(async () => {
    await DB.prepare(`INSERT INTO entries (value) VALUES (?), (?)`)
            .bind(‘aaa’, ‘bbb’)
            .run()
  })
  // Now, all tests will run with a DB with those two values
  it(‘should report 2 entries’, async () => {
    await Worker.fetch(...)
  })
  it(‘should not allow duplicate entries’, async () => {
    await Worker.fetch(...)
  })
])
All the databases for tests are run in-memory, so these are lightning fast. And fast, reliable testing is a big part of building maintainable real-world apps, so we’re thrilled to extend that to D1.
Want access to the private beta?
Feeling inspired?
We love to see what our beta users build or want to build especially when our products are at an early stage. As we march toward an open beta, we’ll be looking specifically for your feedback. We are slowly letting more folks into the beta, but if you haven’t received your “golden ticket” yet with access, sign up here! Once you’ve been invited in, you’ll receive an official welcome email.
Starting a business is hard. And we know that the first few years of your business are crucial to your success.
Cloudflare’s Startup Plan is here to help.
Last year, we piloted a program to a select group of startups for free, with a selection of products that are very high leverage for young startups, early in their product development, like Workers, Stream, and Zero Trust.
Over the past year, startup founders repeatedly wrote into [email protected], and most of these emails followed one of 2 patterns:
A startup would like to request additional products that are not a part of the startup plan, often Workers KV, Pages, Cloudflare for SaaS, R2, Argo, etc.
A startup that is not a part of any accelerator program but would like to get on the startup plan.
Based on this feedback, we are thrilled to announce that today we will be increasing the scope of the program to also include popularly requested products! Beyond that, we’re also super excited to be broadening the eligibility criteria, so more startups can qualify for the plan.
What does the Cloudflare Startup Plan include?
There’s a lot of additional value that’s in the latest version of the plan. Here’s how things have evolved from v1.0:
Cloudflare’s CDN is a distributed network of servers that provides several advantages for a website. By caching website content, Cloudflare helps improve page load speeds, reduce bandwidth usage, and reduce CPU usage on the server.
Cloudflare WAF protects a customer’s Internet properties from common vulnerabilities like SQL injection attacks, cross-site scripting, and cross-site forgery requests, with no changes to its existing infrastructure.
Cloudflare DNS is an enterprise-grade authoritative DNS service that offers the fastest response time, unparalleled redundancy, and advanced security with built-in DDoS mitigation and DNSSEC.
Cloudflare DDoS protection secures websites, applications, and entire networks while ensuring the performance of legitimate traffic is not compromised.
Page Rules allows you to conditionally change zone settings such as security level or rocket loader settings. It is also how cache settings are configured for traffic passing through the zone.
Cloudflare Workers allows developers to augment existing applications or create entirely new ones through a lightweight execution environment without configuring or maintaining infrastructure.
Cloudflare Stream provides out-of-the-box video infrastructure that handles storage, encoding, and delivery. Using the Stream API, customers can build video functionality affordably and with minimal engineering effort.
Cloudflare R2 Storage allows developers to store large amounts of unstructured data without the costly egress bandwidth fees associated with typical cloud storage services.
Workers KV is a global, low-latency, key-value data store. It supports high read volumes with low-latency, making it possible to build highly dynamic APIs and websites which respond as quickly as a cached static file would.
Offers the benefits of Cloudflare’s SSL management to SaaS company’s customers. Allows SaaS customers to use their custom vanity domains while maintaining a branded customer experience, improved SEO rankings, and all the perks of dedicated certificates.
Advanced Certificate Manager is a flexible and customizable way to issue and manage certificates in Cloudflare. Customers use Advanced Certificate Manager when they want something more customizable than Universal SSL but still want the convenience of SSL certificate issuance and renewal.
Resize images for a variety of device types and connections from a single-source master image. Images can be manipulated by dimensions, compression ratios, and format (WebP conversion where supported). It is a feature of Speed→Optimization on the Dashboard.
Cloudflare Images lets you set up an image pipeline in minutes. Build a scalable image pipeline to store, resize, optimize and deliver images in a fast and secure manner.
Argo Smart Routing improves Internet performance by intelligently routing end users through less congested and more reliable paths over the Internet using our network.
Improve application performance and availability by steering traffic away from unhealthy origin servers and dynamically distributing it to the most available and responsive server pools.
Cloudflare Waiting Room allows organizations to route excess users to a custom-branded waiting room, helping preserve customer experience and protect origin servers from being overwhelmed with requests.
Comprehensive email security solution to eliminate the risk from phishing, which is the root cause of damage in 95% of all cybersecurity incidents. Configuration with Google and Microsoft in 5 minutes.
✓
*Product-specific usage limits apply
With the expanded product basket, the Startup Plan v2.0 provides four times the value of the original program. As an added bonus when new Cloudflare products are in beta, participants on the Startup Plan are welcome to share their use case and potentially receive early access.
How to join the Cloudflare Startup Program
Eligibility criteria for startups new to the program
To be eligible for the Startup Plan, your startup must be at an early stage (i.e. raised less than $3 million) and enrolled or recently graduated from a participating accelerator program.
If you are a founder in a participating accelerator program, navigate to the Cloudflare perk from your program’s vendor perk page and follow the instructions there. Those instructions will lead you to this plan page where you can select your program from the list.
If your accelerator program is not on the list, please email us at [email protected] and include the details of your perk manager. We’ll get in touch with them directly.
What if I’m already on the V1 Startup Plan? Can I get access to the products on the V2 plan?
Yes! Startups currently on the Startup Plan will automatically have the additional products added to your accounts in the coming weeks, no action required. This upgrade will apply for the remainder of the year that your company is on the Startup Plan.
If you have any questions about making the most of your plan, drop a line to [email protected] with any questions.
Special Eligibility: Referral Program, Alumni Program, Workers Launchpad
Over our years at Cloudflare, we have had the privilege of working with some remarkable technologists who have gone on to work on extraordinary projects after their time at Cloudflare. Moreover, there are startup founders who interface with teams at Cloudflare, whether through participation in the Cloudflare Community or because they were former coworkers elsewhere.
These startups are now also eligible:
Workers Launchpad funding program: If you are building on Cloudflare Workers, simultaneously apply for the Workers Launchpad funding program here, which will make you eligible for introductions to leading investors, additional mentorship opportunities, and other perks.
Referral Program: “Referred by (include details in comments)” is now an option in the Select Accelerator dropdown menu on the Startup Plan landing page. Please include the email address of your contact at Cloudflare in the comments field. Your account will be upgraded once your contact validates the referral.
Alumni Program: “Cloudflare Alumni” is now also an option in the Select Accelerator dropdown menu.
Questions about the program? Drop us a line at [email protected], and we’ll be in touch.
A few months ago we launched Custom Domains into an open beta. Custom Domains allow you to hook up your Workers to the Internet, without having to deal with DNS records or certificates – just enter a valid hostname and Cloudflare will do the rest! The beta’s over, and Custom Domains are now GA.
Custom Domains aren’t just about a seamless developer experience; they also allow you to build a globally distributed instantly scalable application on Cloudflare’s Developer Platform. That’s because Workers leveraging Custom Domains have no concept of an ‘Origin Server’. There’s no ‘home’ to phone to – and that also means your application can use the power of Cloudflare’s global network to run your application, well, everywhere. It’s truly serverless.
Let’s build “Todo”, but without the servers
Today we’ll start a series of posts outlining a simple todo list application. We’ll start with an API and hook it up to the Internet using Custom Domains.
With Custom Domains, you’re treating the whole network as the application server. Any time a request comes into a Cloudflare data center, Workers are triggered in that data center and connect to resources across the network as needed. Our developers don’t need to think about regions, or replication, or spinning up the right number of instances to handle unforeseen load. Instead, just deploy your Workers and Cloudflare will handle the rest.
For our todo application, we begin by building an API Gateway to perform routing, any authorization checks, and drop invalid requests. We then fan out to each individual use case in a separate Worker, so our teams can independently make updates or add features to each endpoint without a full redeploy of the whole application. Finally, each Worker has a D1 binding to be able to create, read, update, and delete records from the database. All of this happens on Cloudflare’s global network, so your API is truly available everywhere. The architecture will look something like this:
Bootstrap the D1 Database
First off, we’re going to need a D1 database set up, with a schema for our todo application to run on. If you’re not familiar with D1, it’s Cloudflare’s serverless database offering – explained in more detail here. To get started, we use the wrangler d1 command to create a new database:
After executing this command, you will be asked to add a snippet of code to your wrangler.tomlfile that looks something like this:
[[ d1_databases ]]
binding = "db" # i.e. available in your Worker on env.db
database_name = "<todo | custom-database-name>"
database_id = "<UUID>"
Let’s save that for now, and we’ll put these into each of our private microservices in a few moments. Next, we’re going to create our database schema. It’s a simple todo application, so it’ll look something like this, with some seeded data:
db/schema.sql
DROP TABLE IF EXISTS todos;
CREATE TABLE todos (id INTEGER PRIMARY KEY, todo TEXT, todoStatus BOOLEAN NOT NULL CHECK (todoStatus IN (0, 1)));
INSERT INTO todos (todo, todoStatus) VALUES ("Fold my laundry", 0),("Get flowers for mum’s birthday", 0),("Find Nemo", 0),("Water the monstera", 1);
You can bootstrap your new D1 database by running:
Great! We’ve now got a database running entirely on Cloudflare’s global network.
Build the endpoint Workers
To talk to your database, we’ll spin up a series of private microservices for each endpoint in our application. We want to be able to create, read, update, delete, and list our todos. The full source code for each is available here. Below is code from a Worker that lists all our todos from D1.
The Worker ‘todo-list’ needs to be able to access D1 from the environment variable db. To do this, we’ll define the D1 binding in our wrangler.toml file. We also specify that workers_dev is false, preventing a preview from being generated via workers.dev (we want this to be a private microservice).
list/wrangler.toml
name = "todo-list"
main = "src/list.js"
compatibility_date = "2022-09-07"
workers_dev = false
usage_model = "unbound"

[[ d1_databases ]]
binding = "db" # i.e. available in your Worker on env.db
database_name = "<todo | custom-database-name>"
database_id = "UUID"
Finally, use wrangler publish to deploy this microservice.
todo/list on ∞main [!]
› wrangler publish
 ⛅️ wrangler 0.0.0-893830aa
-----------------------------------------------------------------------
Retrieving cached values for account from ../../../node_modules/.cache/wrangler
Your worker has access to the following bindings:
- D1 Databases:
  - db: todo (UUID)
Total Upload: 4.71 KiB / gzip: 1.60 KiB
Uploaded todo-list (0.96 sec)
No publish targets for todo-list (0.00 sec)
Notice that wrangler mentions there are no ‘publish targets’ for todo-list. That’s because we haven’t hooked todo-list up to any HTTP endpoints. That’s fine! We’re going to use Service Bindings to route requests through a gateway worker, as described in the architecture diagram above.
Next, reuse these steps to create similar microservices for each of our create, read, update, and delete endpoints. The source code is available to follow along.
Tying it all together with an API Gateway
Each of our Workers are able to talk to the D1 database, but how can our application talk to our API? We’ll build out a simple API gateway to route incoming requests to the appropriate microservice. For the purposes of our application, we’re using a combination of URL pathname and request method to detect which endpoint is appropriate.
gateway/src/gateway.js
export default {
 async fetch(request, env) {
   try{
     const url = new URL(request.url)
     const idPattern = new URLPattern({ pathname: '/:id' })
     if (idPattern.test(request.url)) {
       switch (request.method){
         case 'GET':
           return await env.get.fetch(request.clone())
         case 'PATCH':
           return await env.update.fetch(request.clone())
         case 'DELETE':
           return await env.delete.fetch(request.clone())
         default:
           return new Response("Unsupported method for endpoint /:id", {status: 405})
       }
     } else if (url.pathname == '/') {
       switch (request.method){
         case 'GET':
           return await env.list.fetch(request.clone())
         case 'POST':
           return await env.create.fetch(request.clone())
         default:
           return new Response("Unsupported method for endpoint /", {status: 405})
       }
     }
     return new Response("Not found. Supported endpoints are /:id and /", {status: 404})
   } catch(e) {
     return new Response(e, {status: 500})
   }
 },
};
With our API gateway all set, we just need to expose our application to the Internet using a Custom Domain, and hook up our Service Bindings, so the gateway Worker can access each appropriate microservice. We’ll set this up in a wrangler.toml.
Next, use wrangler publish to deploy your application to the Cloudflare network. Seconds later, you’ll have a simple, functioning todo API built entirely on Cloudflare’s Developer Platform!
› wrangler publish
 ⛅️ wrangler 0.0.0-893830aa
-----------------------------------------------------------------------
Retrieving cached values for account from ../../../node_modules/.cache/wrangler
Your worker has access to the following bindings:
- Services:
  - get: todo-get
  - delete: todo-delete
  - create: todo-create
  - update: todo-update
  - list: todo-list
Total Upload: 1.21 KiB / gzip: 0.42 KiB
Uploaded todo-gateway (0.62 sec)
Published todo-gateway (0.51 sec)
  todos.radiobox.tv (custom domain - zone name: radiobox.tv)
Natively Global
Since it’s built natively on Cloudflare, you can also include Cloudflare’s security suite in front of the application. If we want to prevent SQL Injection attacks for this endpoint, we can enable the appropriate Managed WAF rules on our todos API endpoint. Alternatively, if we wanted to prevent global access to our API (only allowing privileged clients to access the application), we can simply put Cloudflare Access in front, with custom Access Rules.
With Custom Domains on Workers, you’re able to easily create applications that are native to Cloudflare’s global network, instantly. Best of all, your developers don’t need to worry about maintaining DNS records or certificate renewal – Cloudflare handles it all on their behalf. We’d like to give a huge shout out to the 5,000+ developers who used Custom Domains during the open beta period, and those that gave feedback along the way to make this possible. Can’t wait to see what you build next! As always, if you have any questions or would like to get involved, please join us on Discord.
Tune in next time to see how we can build a frontend for our application. In the meantime, you can play around with the todos API we built today at todos.radiobox.tv.
The Software as a Service (SaaS) model has changed the way we work – 80% of businesses use at least one SaaS application. Instead of investing in building proprietary software or installing and maintaining on-prem licensed software, SaaS vendors provide businesses with out-of-the-box solutions.
SaaS has many benefits over the traditional software model: cost savings, continuous updates and scalability, to name a few. However, any managed solution comes with trade-offs. As a business, one of the biggest challenges in adopting SaaS tooling is loss of customization. Not every business uses software in the same way and as you grow as a SaaS company it’s not long until you get customers saying “if only I could do X”.
Enter Workers for Platforms – Cloudflare’s serverless functions offering for SaaS businesses. With Workers for Platforms, your customers can build custom logic to meet their requirements right into your application.
We’re excited to announce that Workers for Platforms is now in GA for all Enterprise customers! If you’re an existing customer, reach out to your Customer Success Manager (CSM) to get access. For new customers, fill out our contact form to get started.
The conundrum of customization
As a SaaS business invested in capturing the widest market, you want to build a universal solution that can be used by customers of different sizes, in various industries and regions. However, every one of your customers has a unique set of tools and vendors and best practices. A generalized platform doesn’t always meet their needs.
For SaaS companies, once you get in the business of creating customizations yourself, it can be hard to keep up with seemingly never ending requests. You want your engineering teams to focus on building out your core business instead of building and maintaining custom solutions for each of your customer’s use cases.
With Workers for Platforms, you can give your customers the ability to write code that customizes your software. This gives your customers the flexibility to meet their exact use case while also freeing up internal engineering time – it’s a win-win!
How is this different from Workers?
Workers is Cloudflare’s serverless execution environment that runs your code on Cloudflare’s global network. Workers is lightning fast and scalable; running at data centers in 275+ cities globally and serving requests from as close as possible to the end user. Workers for Platforms extends the power of Workers to our customer’s developers!
So, what’s new?
Dispatch Worker: As a platform customer, you want to have full control over how end developer code fits in with your APIs. A Dispatch Worker is written by our platform customers to run their own logic before dispatching (aka routing) to Workers written by end developers. In addition to routing, it can be used to run authentication, create boilerplate functions and sanitize responses.
User Workers: User Workers are written by end developers, that is, our customers’ developers. End developers can deploy User Workers to script automated actions, create integrations or modify response payload to return custom content. Unlike self-managed Function-as-a-Service (FaaS) options, with Workers for Platforms, end developers don’t need to worry about setting up and maintaining their code on any 3rd party platform. All they need to do is upload their code and you – or rather Cloudflare – takes care of the rest.
Unlimited Scripts: Yes, you read that correctly! With hundreds-plus end developers, the existing 100 script limit for Workers won’t cut it for Workers for Platforms customers. Some of our Workers for Platforms customers even deploy a new script each time their end developers make a change to their code in order to maintain version control and to easily revert to a previous state if a bug is deployed.
Dynamic Dispatch Namespaces: If you’ve used Workers before, you may be familiar with a feature we released earlier this year, Service Bindings. Service Bindings are a way for two Workers to communicate with each other. They allow developers to break up their applications into modules that can be chained together. Service Bindings explicitly link two Workers together, and they’re meant for use cases where you know exactly which Workers need to communicate with each other.
Service Bindings don’t work in the Workers for Platforms model because User Workers are uploaded ad hoc. Dynamic Dispatch Namespaces is our solution to this! A Dispatch Namespace is composed of a collection of User Workers. With Dispatch Namespaces, a Dispatch Worker can be used to call any User Worker in a namespace (similar to how Service Bindings work) but without needing to explicitly pre-define the relationship.
Read more about how to use these features below!
How to use Workers for Platforms
Dispatch Workers
Dispatch Workers are the entry point for requests to Workers in a Dispatch Namespace. The Dispatch Worker can be used to run any functions ahead of User Workers. They can make a request to any User Workers in the Dispatch Namespace, and they ultimately handle the routing to User Workers.
Dispatch Workers are created the same way as a regular Worker, except they need a Dispatch Namespace binding in the project’s wrangler.toml configuration file.
In the example below, this Dispatch Worker reads the subdomain from the path and calls the appropriate User Worker. Alternatively you can use KV, D1 or your data store of choice to map identifying parameters from an incoming request to a User Worker.
export default {
 async fetch(request, env) {
   try {
       // parse the URL, read the subdomain
       let worker_name = new URL(request.url).host.split('.')[0]
       let user_worker = env.dispatcher.get(worker_name)
       return user_worker.fetch(request)
   } catch (e) {
       if (e.message == 'Error: Worker not found.') {
           // we tried to get a worker that doesn't exist in our dispatch namespace
           return new Response('', {status: 404})
       }
       // this could be any other exception from `fetch()` *or* an exception
       // thrown by the called worker (e.g. if the dispatched worker has
       // `throw MyException()`, you could check for that here).
       return new Response(e.message, {status: 500})
   }
 }

}
Uploading User Workers
User Workers must be uploaded to a Dispatch Namespace through the Cloudflare API (wrangler support coming soon!). This code snippet below uses a simple HTML form to take in a script and customer id and then uploads it to the Dispatch Namespace.
It’s that simple. With Dispatch Namespaces and Dispatch Workers, we’re giving you the building blocks to customize your SaaS applications. Along with the Platforms APIs, we’re also releasing a Workers for Platforms UI on the Cloudflare dashboard where you can view your Dispatch Namespaces, search scripts and view analytics for User Workers.
We’re releasing Workers for Platforms to all Cloudflare Enterprise customers. If you’re interested, reach out to your Customer Success Manager (CSM) to get access. To get started, take a look at our Workers for Platforms starter project and developer documentation.
We also have plans to release this down to the Workers Paid plan. Stay tuned on the Cloudflare Discord (channel name: workers-for-platforms-beta) for updates.
What’s next?
We’ve heard lots of great feature requests from our early Workers for Platforms customers. Here’s a preview of what’s coming next on the roadmap:
Fine-grained controls over User Workers: custom script limits, allowlist/blocklist for fetch requests
GraphQL and Logs: Metrics for User Workers by tag
Plug and play Platform Development Kit
Tighter integration with Cloudflare for SaaS custom domains
If you have specific feature requests in mind, please reach out to your CSM or get in touch through the Discord!
R2 gives developers object storage, without the egress fees. Before R2, cloud providers taught us to expect a data transfer tax every time we actually used the data we stored with them. Who stores data with the goal of never reading it? No one. Yet, every time you read data, the egress tax is applied. R2 gives developers the ability to access data freely, breaking the ecosystem lock-in that has long tied the hands of application builders.
In May 2022, we launched R2 into open beta. In just four short months we’ve been overwhelmed with over 12k developers (and rapidly growing) getting started with R2. Those developers came to us with a wide range of use cases from podcast applications to video platforms to ecommerce websites, and users like Vecteezy who was spending six figures in egress fees. We’ve learned quickly, gotten great feedback, and today we’re excited to announce R2 is now generally available.
We wouldn’t ask you to bet on tech we weren’t willing to bet on ourselves. While in open beta, we spent time moving our own products to R2. One such example, Cloudflare Images, proudly serving thousands of customers in production, is now powered by R2.
What can you expect from R2?
S3 Compatibility
R2 gives developers a familiar interface for object storage, the S3 API. WIth S3 Compatibility, you can easily migrate your applications and start taking advantage of what R2 has to offer right out of the gate.
Let’s take a look at some basic data operations in javascript. To try this out on your own, you’ll need to generate an Access Key.
// First we import our bindings as usual
import {
  S3Client,
  ListBucketsCommand,
} from "@aws-sdk/client-s3";

// Then we create a new client. Note that while R2 requires a region for S3 compatibility, only “auto” is supported
const S3 = new S3Client({
  region: "auto",
  endpoint: `https://${ACCOUNT_ID}.r2.cloudflarestorage.com`,
  credentials: {
    accessKeyId: ACCESS_KEY_ID, //  fill in your own
    secretAccessKey: SECRET_ACCESS_KEY, // fill in your own
  },
});

// And now we can use our client to list associated buckets just like we would with any other S3 compatible object storage
console.log(
  await S3.send(
    new ListBucketsCommand('')
  )
);
Regardless of the language, the S3 API offers familiarity. We have examples in Go, Java, PHP, and Ruby.
Region: Automatic
We don’t want to live in a world where developers are spending time looking into a crystal ball and predicting where application traffic might come from. Choosing a region as the first step in application development forces optimization decisions long before the first users show up.
While S3 compatibility requires you to specify a region, the only region we support is ‘auto’. Today, R2 automatically selects a bucket location in the closest available region to the create bucket request. If I create a bucket from my home in Austin, that bucket will live in the closest available R2 region to Austin.
In the future, R2 will use data access patterns to automatically optimize where data is stored for the best user experience.
Cloudflare Workers Integration
The Workers platform offers developers powerful compute across Cloudflare’s network. When you deploy on Workers, your code is deployed to Cloudflare’s 280+ locations across the globe, automatically. When paired with R2, Workers allows developers to add custom logic around their data without any performance overhead. Workers is built on isolates and not containers, and as a result you don’t have to deal with lengthy cold starts.
Let’s try creating a simple REST API for an R2 bucket! First, create your bucket and then add an R2 binding to your worker.
export default {
  async fetch(request, env) {
    const url = new URL(request.url);
    const key = url.pathname.slice(1); // we’ll derive a key from the url path

    switch (request.method) {
      // For writes, we capture the request body and write that out to our bucket under the associated key
      case 'PUT':
        await env.MY_BUCKET.put(key, request.body);
        return new Response(`Put ${key} successfully!`);

      // For reads, we’ll use our key to perform a lookup
      case 'GET':
        const object = await env.MY_BUCKET.get(key);

        // if we don’t find the given key we’ll return a 404 error
        if (object === null) {
          return new Response('Object Not Found', { status: 404 });
        }

        const headers = new Headers();
        object.writeHttpMetadata(headers);
        headers.set('etag', object.httpEtag);

        return new Response(object.body, {
          headers,
        });
    }
  },
};
Through this Workers API, we can add all sorts of useful logic to the hot path of a R2 request.
Presigned URLs
Sometimes you’ll want to give your users permissions to specific objects in R2 without requiring them to jump through hoops. Through pre-signed URLs you can delegate your permissions to your users for any unique combination of object and action. Mint a pre-signed URL to let a user upload a file or share a file without giving access to the entire bucket.
import {
  S3Client,
  PutObjectCommand
} from "@aws-sdk/client-s3";

import { getSignedUrl } from "@aws-sdk/s3-request-presigner";

const S3 = new S3Client({
  region: "auto",
  endpoint: `https://${ACCOUNT_ID}.r2.cloudflarestorage.com`,
  credentials: {
    accessKeyId: ACCESS_KEY_ID,
    secretAccessKey: SECRET_ACCESS_KEY,
  },
});

// With getSignedUrl we can produce a custom url with a one hour expiration which will allow our end user to upload their dog pic
console.log(
  await getSignedUrl(S3, new PutObjectCommand({Bucket: 'my-bucket-name', Key: 'dog.png'}), { expiresIn: 3600 })
)
Presigned URLs make it easy for developers to build applications that let end users safely access R2 directly.
Public buckets
Enabling public access for a R2 bucket allows you to expose that bucket to unauthenticated requests. While doing so on its own is of limited use, when those buckets are linked to a domain under your account on Cloudflare you can enable other Cloudflare features such as Access, Cache and bot management seamlessly on top of your data in R2.
Bottom line: public buckets help to bridge the gap between domain oriented Cloudflare features and the buckets you have in R2.
Transparent Pricing
R2 will never charge for egress. The pricing model depends on three factors alone: storage volume, Class A operations (writes, lists) and Class B operations (reads).
Storage is priced at $0.015 / GB, per month.
Class A operations cost $4.50 / million.
Class B operations cost $0.36 / million.
But before you’re ready to start paying for R2, we allow you to get up and running at absolutely no cost. The included usage is as follows:
10 GB-months of stored data
1,000,000 Class A operations, per month
10,000,000 Class B operations, per month
What’s next?
Making R2 generally available is just the beginning of our object storage journey. We’re excited to share what we plan to build next.
Object Lifecycles
In the future R2 will allow developers to set policies on objects. For example, setting a policy that deletes an object 60 days after it was last accessed. Object Lifecycles pushes object management down to the object store.
Jurisdictional Restrictions
While we don’t have plans to support regions explicitly, we know that data locality is important for a good deal of compliance use cases. Jurisdictional restrictions will allow developers to set a jurisdiction like the ‘EU’ that would prevent guarantee data from leavingwould not leave the jurisdiction.
Live Migration without Downtime
For large datasets, migrations are live and ongoing, as it takes time to move data over. Cache reserve is an easy way to quickly migrate your assets into a managed R2 instance to reduce your egress costs at the touch of a button. In the future, we’ll be extending this mechanism so that you can migrate any of your existing S3 object storage buckets to R2.
We invite everyone to sign up and get started with R2 today. Join the growing community of developers building on Cloudflare. If you have any feedback or questions, find us on our Discord server here! We can’t wait to see what you build.
We rely on technology to help us on a daily basis – if you are not good at keeping track of time, your calendar can remind you when it’s time to prepare for your next meeting. If you made a reservation at a really nice restaurant, you don’t want to miss it! You appreciate the app to remind you a day before your plans the next evening.
However, who tells the application when it’s the right time to send you a notification? For this, we generally rely on scheduled events. And when you are relying on them, you really want to make sure that they occur. Turns out, this can get difficult. The scheduler and storage backend need to be designed with scale in mind – otherwise you may hit limitations quickly.
Workers, Durable Objects, and Alarms are actually a perfect match for this type of workload. Thanks to the distributed architecture of Durable Objects and their storage, they are a reliable and scalable option. Each Durable Object has access to its own isolated storage and alarm scheduler, both being automatically replicated and failover in case of failures.
There are many use cases where having a reliable scheduler can come in handy: running a webhook service, sending emails to your customers a week after they sign up to keep them engaged, sending invoices reminders, and more!
Today, we’re going to show you how to build a scalable service that will schedule HTTP requests on a specific schedule or as one-off at a specific time as a way to guide you through any use case that requires scheduled events.
Quick intro into the application stack
Before we dive in, here are some of the tools we’re going to be using today:
Wrangler – CLI tool to develop and publish Workers
The application is going to have following components:
Scheduling system API to accept scheduled requests and manage Durable Objects
Unique Durable Object per scheduled request, each with
Storage – keeping the request metadata, such as URL, body, or headers.
Alarm – a timer (trigger) to wake Durable Object up.
While we will focus on building the application, the Cloudflare global network will take care of the rest – storing and replicating our data, and making sure to wake our Durable Objects up when the time’s right. Let’s build it!
Initialize new Workers project
Get started by generating a completely new Workers project using the wrangler init command, which makes creating new projects quick & easy.
From my personal experience, at least a draft of TypeScript types significantly helps to be more productive down the road, so let’s prepare and describe our scheduled request in advance. Create a file types.ts in src directory and paste the following TypeScript definitions.
src/types.ts
export interface Env {
    DO_REQUEST: DurableObjectNamespace
}

export interface ScheduledRequest {
  url: string // URL of the request
  triggerAt?: number // optional, unix timestamp in milliseconds, defaults to `new Date()`
  requestInit?: RequestInit // optional, includes method, headers, body
}
A scheduled request Durable Object class & alarm
Based on our architecture design, each scheduled request will be saved into its own Durable Object, effectively separating storage and alarms from each other and allowing our scheduling system to scale horizontally – there is no limit to the number of Durable Objects we create.
In the end, the Durable Object class is a matter of a couple of lines. The code snippet below accepts and saves the request body to a persistent storage and sets the alarm timer. Workers runtime will wake up the Durable Object and call the alarm() method to process the request.
The alarm method reads the scheduled request data from the storage, then processes the request, and in the end reschedules itself in case it’s configured to be executed on a recurring schedule.
src/request-durable-object.ts
import { ScheduledRequest } from "./types";

export class RequestDurableObject {
  id: string|DurableObjectId
  storage: DurableObjectStorage

  constructor(state:DurableObjectState) {
    this.storage = state.storage
    this.id = state.id
  }

    async fetch(request:Request) {
    // read scheduled request from request body
    const scheduledRequest:ScheduledRequest = await request.json()

    // save scheduled request data to Durable Object storage, set the alarm, and return Durable Object id
    this.storage.put("request", scheduledRequest)
    this.storage.setAlarm(scheduledRequest.triggerAt || new Date())
    return new Response(JSON.stringify({
      id: this.id.toString()
    }), {
      headers: {
        "content-type": "application/json"
      }
    })
  }

  async alarm() {
    // read the scheduled request from Durable Object storage
    const scheduledRequest:ScheduledRequest|undefined = await this.storage.get("request")

    // call fetch on scheduled request URL with optional requestInit
    if (scheduledRequest) {
      await fetch(scheduledRequest.url, scheduledRequest.requestInit ? webhook.requestInit : undefined)

      // cleanup scheduled request once done
      this.storage.deleteAll()
    }
  }
}
Wrangler configuration
Once we have the Durable Object class, we need to create a Durable Object binding by instructing Wrangler where to find it and what the exported class name is.
wrangler.toml
name = "durable-objects-request-scheduler"
main = "src/index.ts"
compatibility_date = "2022-08-02"

# added Durable Objects configuration
[durable_objects]
bindings = [
  { name = "DO_REQUEST", class_name = "RequestDurableObject" },
]

[[migrations]]
tag = "v1"
new_classes = ["RequestDurableObject"]
Scheduling system API
The API Worker will accept POST HTTP methods only, and is expecting a JSON body with scheduled request data – what URL to call, optionally what method, headers, or body to send. Any other method than POST will return 405 – Method Not Allowed HTTP error.
HTTP POST /:scheduledRequestId? will create or override a scheduled request, where :scheduledRequestId is optional Durable Object ID returned from a scheduling system API before.
src/index.ts
import { Env } from "./types"
export { RequestDurableObject } from "./request-durable-object"

export default {
    async fetch(
        request: Request,
        env: Env
    ): Promise<Response> {
        if (request.method !== "POST") {
            return new Response("Method Not Allowed", {status: 405})
        }

        // parse the URL and get Durable Object ID from the URL
        const url = new URL(request.url)
        const idFromUrl = url.pathname.slice(1)

        // construct the Durable Object ID, use the ID from pathname or create a new unique id
        const doId = idFromUrl ? env.DO_REQUEST.idFromString(idFromUrl) : env.DO_REQUEST.newUniqueId()

        // get the Durable Object stub for our Durable Object instance
        const stub = env.DO_REQUEST.get(doId)

        // pass the request to Durable Object instance
        return stub.fetch(request)
    },
}
It’s good to mention that the script above does not implement any listing of scheduled or processed webhooks. Depending on how the scheduling system would be integrated, you can save each created Durable Object ID to your existing backend, or write your own registry – using one of the Workers storage options.
Starting a local development server and testing our application
We are almost done! Before we publish our scheduler system to the Cloudflare edge, let’s start Wrangler in a completely local mode to run a couple of tests against it and to see it in action – which will work even without an Internet connection!
wrangler dev --local
The development server is listening on localhost:8787, which we will use for scheduling our first request. The JSON request payload should match the TypeScript schema we defined in the beginning – required URL, and optional triggerEverySeconds number or triggerAt unix timestamp. When only the required URL is passed, the request will be dispatched right away.
An example of request payload that will send a GET request to https://example.com every 30 seconds.
From the wrangler logs we can see the scheduled request ID 000000018265a5ecaa5d3c0ab6a6997bf5638fdcb1a8364b269bd2169f022b0f is being triggered in 30s intervals.
Need to double the interval? No problem, just send a new POST request and pass the request ID as a pathname.
Every scheduled request gets a unique Durable Object ID with its own storage and alarm. As we demonstrated, the ID becomes handy when you need to change the settings of the scheduled request, or to deschedule them completely.
Publishing to the network
Following command will bundle our Workers application, export and bind Durable Objects, and deploy it to our workers.dev subdomain.
wrangler publish
That’s it, we are live! 🎉 The URL of your deployment is shown in the Workers logs. In a reasonably short period of time we managed to write our own scheduling system that is ready to handle requests at scale.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.