Tag Archives: Featured

Amazon Nova Reel 1.1: Featuring up to 2-minutes multi-shot videos

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/amazon-nova-reel-1-1-featuring-up-to-2-minutes-multi-shot-videos/

At re:Invent 2024, we announced Amazon Nova models, a new generation of foundation models (FMs), including Amazon Nova Reel, a video generation model that creates short videos from text descriptions and optional reference images (together, the “prompt”).

Today, we introduce Amazon Nova Reel 1.1, which provides quality and latency improvements in 6-second single-shot video generation, compared to Amazon Nova Reel 1.0. This update lets you generate multi-shot videos up to 2-minutes in length with consistent style across shots. You can either provide a single prompt for up to a 2-minute video composed of 6-second shots, or design each shot individually with custom prompts. This gives you new ways to create video content through Amazon Bedrock.

Amazon Nova Reel enhances creative productivity, while helping to reduce the time and cost of video production using generative AI. You can use Amazon Nova Reel to create compelling videos for your marketing campaigns, product designs, and social media content with increased efficiency and creative control. For example, in advertising campaigns, you can produce high-quality video commercials with consistent visuals and timing using natural language.

To get started with Amazon Nova Reel 1.1 
If you’re new to using Amazon Nova Reel models, go to the Amazon Bedrock console, choose Model access in the navigation panel and request access to the Amazon Nova Reel model. When you get access to Amazon Nova Reel, it applies both to 1.0 and 1.1.

After gaining access, you can try Amazon Nova Reel 1.1 directly from the Amazon Bedrock console, AWS SDK, or AWS Command Line Interface (AWS CLI).

To test the Amazon Nova Reel 1.1 model in the console, choose Image/Video under Playgrounds in the left menu pane. Then choose Nova Reel 1.1 as the model and input your prompt to generate video.

Amazon Nova Reel 1.1 offers two modes:

  • Multishot Automated – In this mode, Amazon Nova Reel 1.1 accepts a single prompt of up to 4,000 characters and produces a multi-shot video that reflects that prompt. This mode doesn’t accept an input image.
  • Multishot Manual – For those who desire more direct control over a video’s shot composition, with manual mode (also referred to as storyboard mode), you can specify a unique prompt for each individual shot. This mode does accept an optional starting image for each shot. Images must have a resolution of 1280×720. You can provide images in base64 format or from an Amazon Simple Storage Service (Amazon S3) location.

For this demo, I use the AWS SDK for Python (Boto3) to invoke the model using the Amazon Bedrock API and StartAsyncInvoke operation to start an asynchronous invocation and generate the video. I used GetAsyncInvoke to check on the progress of a video generation job.

This Python script creates a 120-second video using MULTI_SHOT_AUTOMATED mode as TaskType parameter from this text prompt, created by Nitin Eusebius.

import random
import time

import boto3

AWS_REGION = "us-east-1"
MODEL_ID = "amazon.nova-reel-v1:1"
SLEEP_SECONDS = 15  # Interval at which to check video gen progress
S3_DESTINATION_BUCKET = "s3://<your bucket here>"

video_prompt_automated = "Norwegian fjord with still water reflecting mountains in perfect symmetry. Uninhabited wilderness of Giant sequoia forest with sunlight filtering between massive trunks. Sahara desert sand dunes with perfect ripple patterns. Alpine lake with crystal clear water and mountain reflection. Ancient redwood tree with detailed bark texture. Arctic ice cave with blue ice walls and ceiling. Bioluminescent plankton on beach shore at night. Bolivian salt flats with perfect sky reflection. Bamboo forest with tall stalks in filtered light. Cherry blossom grove against blue sky. Lavender field with purple rows to horizon. Autumn forest with red and gold leaves. Tropical coral reef with fish and colorful coral. Antelope Canyon with light beams through narrow passages. Banff lake with turquoise water and mountain backdrop. Joshua Tree desert at sunset with silhouetted trees. Iceland moss- covered lava field. Amazon lily pads with perfect symmetry. Hawaiian volcanic landscape with lava rock. New Zealand glowworm cave with blue ceiling lights. 8K nature photography, professional landscape lighting, no movement transitions, perfect exposure for each environment, natural color grading"

bedrock_runtime = boto3.client("bedrock-runtime", region_name=AWS_REGION)
model_input = {
    "taskType": "MULTI_SHOT_AUTOMATED",
    "multiShotAutomatedParams": {"text": video_prompt_automated},
    "videoGenerationConfig": {
        "durationSeconds": 120,  # Must be a multiple of 6 in range [12, 120]
        "fps": 24,
        "dimension": "1280x720",
        "seed": random.randint(0, 2147483648),
    },
}

invocation = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={"s3OutputDataConfig": {"s3Uri": S3_DESTINATION_BUCKET}},
)

invocation_arn = invocation["invocationArn"]
job_id = invocation_arn.split("/")[-1]
s3_location = f"{S3_DESTINATION_BUCKET}/{job_id}"
print(f"\nMonitoring job folder: {s3_location}")

while True:
    response = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
    status = response["status"]
    print(f"Status: {status}")
    if status != "InProgress":
        break
    time.sleep(SLEEP_SECONDS)

if status == "Completed":
    print(f"\nVideo is ready at {s3_location}/output.mp4")
else:
    print(f"\nVideo generation status: {status}")

After the first invocation, the script periodically checks the status until the creation of the video has been completed. I pass a random seed to get a different result each time the code runs.

I run the script:

Status: InProgress
. . .
Status: Completed
Video is ready at s3://<your bucket here>/<job_id>/output.mp4

After a few minutes, the script is completed and prints the output Amazon S3 location. I download the output video using the AWS CLI:

aws s3 cp s3://<your bucket here>/<job_id>/output.mp4 output_automated.mp4

This is the video that this prompt generated:

In the case of MULTI_SHOT_MANUAL mode as TaskType parameter, with a prompt for multiples shots and a description for each shot, it is not necessary to add the variable durationSeconds.

Using the prompt for multiples shots, created by Sanju Sunny.

I run Python script:

import random
import time

import boto3


def image_to_base64(image_path: str):
    """
    Helper function which converts an image file to a base64 encoded string.
    """
    import base64

    with open(image_path, "rb") as image_file:
        encoded_string = base64.b64encode(image_file.read())
        return encoded_string.decode("utf-8")


AWS_REGION = "us-east-1"
MODEL_ID = "amazon.nova-reel-v1:1"
SLEEP_SECONDS = 15  # Interval at which to check video gen progress
S3_DESTINATION_BUCKET = "s3://<your bucket here>"

video_shot_prompts = [
    # Example of using an S3 image in a shot.
    {
        "text": "Epic aerial rise revealing the landscape, dramatic documentary style with dark atmospheric mood",
        "image": {
            "format": "png",
            "source": {
                "s3Location": {"uri": "s3://<your bucket here>/images/arctic_1.png"}
            },
        },
    },
    # Example of using a locally saved image in a shot
    {
        "text": "Sweeping drone shot across surface, cracks forming in ice, morning sunlight casting long shadows, documentary style",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_2.png")},
        },
    },
    {
        "text": "Epic aerial shot slowly soaring forward over the glacier's surface, revealing vast ice formations, cinematic drone perspective",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_3.png")},
        },
    },
    {
        "text": "Aerial shot slowly descending from high above, revealing the lone penguin's journey through the stark ice landscape, artic smoke washes over the land, nature documentary styled",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_4.png")},
        },
    },
    {
        "text": "Colossal wide shot of half the glacier face catastrophically collapsing, enormous wall of ice breaking away and crashing into the ocean. Slow motion, camera dramatically pulling back to reveal the massive scale. Monumental waves erupting from impact.",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_5.png")},
        },
    },
    {
        "text": "Slow motion tracking shot moving parallel to the penguin, with snow and mist swirling dramatically in the foreground and background",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_6.png")},
        },
    },
    {
        "text": "High-altitude drone descent over pristine glacier, capturing violent fracture chasing the camera, crystalline patterns shattering in slow motion across mirror-like ice, camera smoothly aligning with surface.",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_7.png")},
        },
    },
    {
        "text": "Epic aerial drone shot slowly pulling back and rising higher, revealing the vast endless ocean surrounding the solitary penguin on the ice float, cinematic reveal",
        "image": {
            "format": "png",
            "source": {"bytes": image_to_base64("arctic_8.png")},
        },
    },
]

bedrock_runtime = boto3.client("bedrock-runtime", region_name=AWS_REGION)
model_input = {
    "taskType": "MULTI_SHOT_MANUAL",
    "multiShotManualParams": {"shots": video_shot_prompts},
    "videoGenerationConfig": {
        "fps": 24,
        "dimension": "1280x720",
        "seed": random.randint(0, 2147483648),
    },
}

invocation = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={"s3OutputDataConfig": {"s3Uri": S3_DESTINATION_BUCKET}},
)

invocation_arn = invocation["invocationArn"]
job_id = invocation_arn.split("/")[-1]
s3_location = f"{S3_DESTINATION_BUCKET}/{job_id}"
print(f"\nMonitoring job folder: {s3_location}")

while True:
    response = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
    status = response["status"]
    print(f"Status: {status}")
    if status != "InProgress":
        break
    time.sleep(SLEEP_SECONDS)

if status == "Completed":
    print(f"\nVideo is ready at {s3_location}/output.mp4")
else:
    print(f"\nVideo generation status: {status}")

As in the previous demo, after a few minutes, I download the output using the AWS CLI:
aws s3 cp s3://<your bucket here>/<job_id>/output.mp4 output_manual.mp4

This is the video that this prompt generated:

More creative examples
When you use Amazon Nova Reel 1.1, you’ll discover a world of creative possibilities. Here are some sample prompts to help you begin:

Color Burst, created by Nitin Eusebius

prompt = "Explosion of colored powder against black background. Start with slow-motion closeup of single purple powder burst. Dolly out revealing multiple powder clouds in vibrant hues colliding mid-air. Track across spectrum of colors mixing: magenta, yellow, cyan, orange. Zoom in on particles illuminated by sunbeams. Arc shot capturing complete color field. 4K, festival celebration, high-contrast lighting"

Shape Shifting, created by Sanju Sunny

prompt = "A simple red triangle transforms through geometric shapes in a journey of self-discovery. Clean vector graphics against white background. The triangle slides across negative space, morphing smoothly into a circle. Pan left as it encounters a blue square, they perform a geometric dance of shapes. Tracking shot as shapes combine and separate in mathematical precision. Zoom out to reveal a pattern formed by their movements. Limited color palette of primary colors. Precise, mechanical movements with perfect geometric alignments. Transitions use simple wipes and geometric shape reveals. Flat design aesthetic with sharp edges and solid colors. Final scene shows all shapes combining into a complex mandala pattern."

All example videos have music added manually before uploading, by the AWS Video team.

Things to know
Creative control – You can use this enhanced control for lifestyle and ambient background videos in advertising, marketing, media, and entertainment projects. Customize specific elements such as camera motion and shot content, or animate existing images.

Modes considerations –  In automated mode, you can write prompts up to 4,000 characters. For manual mode, each shot accepts prompts up to 512 characters, and you can include up to 20 shots in a single video. Consider planning your shots in advance, similar to creating a traditional storyboard. Input images must match the 1280×720 resolution requirement. The service automatically delivers your completed videos to your specified S3 bucket.

Pricing and availability – Amazon Nova Reel 1.1 is available in Amazon Bedrock in the US East (N. Virginia) AWS Region. You can access the model through the Amazon Bedrock console, AWS SDK, or AWS CLI. As with all Amazon Bedrock services, pricing follows a pay-as-you-go model based on your usage. For more information, refer to Amazon Bedrock pricing.

Ready to start creating with Amazon Nova Reel? Visit the Amazon Nova Reel AWS AI Service Cards to learn more and dive into the Generating videos with Amazon Nova. Explore Python code examples in the Amazon Nova model cookbook repository, enhance your results using the Amazon Nova Reel prompting best practices, and discover video examples in the Amazon Nova Reel gallery—complete with the prompts and reference images that brought them to life.

The possibilities are endless, and we look forward to seeing what you create! Join our growing community of builders at community.aws, where you can create your BuilderID, share your video generation projects, and connect with fellow innovators.

Eli


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
Escaping Egress: Hidden Cloud Fees Every CFO Should Know

Post Syndicated from Marc Suidan original https://www.backblaze.com/blog/escaping-egress-hidden-cloud-fees-every-cfo-should-know/

A decorative image showing many clouds connected by a dotted line.

As the saying goes, no one ever got fired for using AWS—but we should revisit that truism. In the era of the open cloud, smart enterprise-level companies are leveraging best-of-breed cloud providers to reduce costs and enhance their cloud stack with specialists. What does that mean, practically speaking? The ability to reduce one of your biggest line item expenses by up to 80%. 

As a CFO, I’m focused on strategically balancing operational expenses (OpEx) with a constant zero-based budgeting approach so my capital either fuels profitable growth or flows to free cash flows so I can drive shareholder value. Cloud storage, while essential, can be a significant cost center, and its billing structures often lack the transparency you need for effective financial management. My goal here is to demystify cloud storage costs, with a particular emphasis on the often-overlooked egress fees, and outline strategies for controlling these expenses.

Understanding the true cost of the cloud

The cost of cloud storage involves paying for data storage. However, the nuances of billing can vary significantly depending on usage patterns. We call an AWS bill a “cloud storage” bill, but it also includes a wide variety of configurable services, including compute, security, networking, analytics, database, and AI and machine learning (AI/ML) tools. 

Consider a company that relies heavily on streaming media. Their primary cost driver is supporting a vast library of content for on-demand streaming. According to EY, cloud hosting for a typical software as a service (SaaS) company costs usually account for 6%-12% of revenue. For businesses with substantial video media assets, just storage expenses can consume a considerable portion of revenue. According to Coughlin and Associates, archiving and preservation accounts for the highest slice of cloud storage spending in the media and entertainment space.

Understanding your cloud bill is easier said than done

Crucial—but difficult to actualize. Cloud storage bills from providers like Amazon are so complex they’re regularly 40+ pages. According to a report from CloudZero, when asked how well they can attribute cloud spend to different aspects of their business (e.g., customers, products, features), 42% of respondents said they’re only able to give an estimate. Even worse, over 20% said they have little to no idea how much different aspects of their business cost.

This complexity has spawned an entire industry specialized in reducing cloud bills, and many enterprise companies have a job role dedicated to it. In my experience, even the best of those that occupy that job role have difficulty parsing the complexity.

Egress fees and other hidden charges: Unveiling the financial drain

While storage costs are relatively straightforward, it’s the hidden fees that can significantly impact the bottom line. Egress fees, incurred when data is transferred out of the cloud, are a prime example. These fees often lack transparency, making accurate budgeting and forecasting difficult. And, if you’re running applications in the cloud, you can’t avoid them: Users need to be able to move their data around. A recent survey indicated that 56% of IT professionals consider egress fees excessive, highlighting a widespread concern within the industry. At Backblaze, over 94% of our cloud storage customers were not charged any egress fees in 2024.

Beyond egress fees, other charges can further complicate cloud billing. These include minimum storage duration fees and tiered pricing models. I’ve seen firsthand how a lack of clarity can hinder financial planning. As I often say to my team, “We can’t optimize what we can’t understand.”

Overcoming cloud migration obstacles: A financial perspective

Given these cost considerations, exploring alternative cloud providers is a financially prudent strategy. I recognize that change can be perceived as disruptive. There’s often a concern about migration complexity and potential risks. Some organizations become so entrenched with a particular provider that they’re hesitant to consider alternatives, even when faced with substantial cost disadvantages in their steady-state cloud bills.   

But, why the specific fear of cloud migration? There are always ways to manage the risk. In the grander scheme of IT and tech complexity, re-pointing an S3 standard API is considered an extremely low risk and low complexity effort. This is not like implementing a new ERP or data warehouse. It’s pretty straight forward, and your tech teams will have to make some time for a proof of concept and some testing. 

The second big blocker is understanding who you are working with from a reputational and security standpoint. Data is the most precious asset for most companies nowadays. How long has the company been around? How many customers do they have? What is the net retention revenue (NRR)? Any history of cyber breaches? And which information security programs and certifications are in place?

Moving to the economics, the back-of-napkin math on the potential financial benefits of switching providers can be substantial. Reducing cloud storage costs directly impacts profitability. For example, if a video media company with storage costs representing 6% of revenue could cut those costs by 80%, that would translate to a 4.8% reduction in overall revenue costs. For a company with a 10% operating margin, this could increase it to 14.8%. That is a very substantial profitability improvement!

I have personally operated and advised companies with hyperscaler invoices from the likes of AWS ranging from $4 million to $7 million annually. Reducing those expenses isn’t just incremental improvement; it’s a game-changer. In some cases, the return on investment (ROI) from migrating to a more cost-effective solution, including reduced egress fees, can be realized in as little as one quarter.

Driving financial performance through cloud optimization

As CFOs, we have a responsibility to scrutinize cloud spending and ensure it aligns with our financial objectives. This requires a deep understanding of cloud billing models, particularly the impact of egress fees. By demanding transparency, rigorously evaluating alternatives, and embracing change, we can effectively manage cloud costs and enhance shareholder value. It’s imperative to foster a culture of agility within our organizations to facilitate necessary changes. The potential financial rewards are significant, and proactive cloud cost management is a key driver of improved financial performance.

The post Escaping Egress: Hidden Cloud Fees Every CFO Should Know appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Meet the AWS News Blog team!

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/meet-the-aws-news-blog-team/

Now that Jeff Barr has retired from the AWS News Blog as of December last year, the AWS News Blog team will keep sharing the most important and impactful AWS product launches the moment they become available. I want to quote Jeff’s last comment on the future of the News Blog again:

Going forward, the team will continue to grow and the goal remains the same: to provide our customers with carefully chosen, high-quality information about the latest and most meaningful AWS launches. The blog is in great hands and this team will continue to keep you informed even as the AWS pace of innovation continues to accelerate.

Since 2016, Jeff has been building the AWS News Blog as a team. Currently, we’re a group of 11 bloggers working in North America, South America, Asia, Europe, and Africa. We co-work with AWS product teams, testing new features firsthand on behalf of customers, and delivering key details in the News Blog the way Jeff has always done.

The Leadership Principles for AWS News Bloggers that Jeff shared on LinkedIn are a textbook for anyone writing for customers in tech companies. They’re the fundamentals that can help you understand and get started blogging quickly, and we’ll continue to stick to these principles with our team. This is why the AWS News Blog is different from other tech companies’ product news channels.

Voices from blog writers
You may be familiar with the names of News Blog writers, but you may not have had the chance to hear about them. Let us introduce ourselves!

Channy Yun (윤석찬)

I’m honored to continue Jeff’s legacy as a new lead blogger of the News Blog team; he is my role model. When I joined AWS in 2014, the first thing I did was to create the AWS Korea Blog and I started translating Jeff’s blog posts into the Korean language. During the journey, I learned how to write accurate, honest, and powerful guides to help customers get started with new AWS products and features.

Danilo Poccia

Since my first News Blog post in 2018, I have learned so much by being part of this team. Working with product managers and service teams is always an amazing experience. I am interested in serverless, event-driven architectures, and AI/ML. It’s incredible how technologies like generative AI are becoming part of software development implicitly (through AI-enabled development tools) and explicitly (by using models in code).

Sébastien Stormacq

I’m fortunate to have been a part of this team since 2019. When I don’t write posts, I produce episodes of the AWS Developers Podcast and le podcast AWS en français. I also work with the teams for Amazon EC2 Mac, AWS SDK for Swift, and the CodeBuild and CodeArtifact teams trying to make the AWS Cloud easier to use for Apple developers. My pet project is the Swift Runtime for AWS Lambda.

Veliswa Boya

The Amazon Leadership Principles (LPs) guide all that we do here at AWS, including the work we do as authors of the News Blog. As a developer advocate, I’ve taken the guidance of the LPs and used it to guide members of the AWS community who are looking to create technical content, especially those new in their technical content creation journey.

Donnie Prakoso

Just like brewing coffee, being a blog author has been a mix of fun, challenge, and reward. I’ve been particularly fortunate to observe how customer obsession is built into AWS teams. I’ve seen how they work backwards, transforming your feedback into services or features. I genuinely hope that you enjoy reading our articles and look forward to the next chapter of the News Blog team.

Esra Kayabali

As an author, I’m committed to delivering timely information about the latest AWS innovations and launches to our global audience of builders, developers, and technology enthusiasts. I understand the importance of providing clear, accurate, and actionable content that helps you use AWS services effectively. Happy reading everyone!

Matheus Guimaraes

My specialties are .NET development and microservices, but I’ve always been a jack-of-all-trades and writing for this blog helps me to keep my knife sharp across all corners of modern technology, while also helping others do the same. Thousands of people read the AWS News Blog and use it as a go-to source to keep up with what’s new and to help them make decisions, so I know that what we are doing is meaningful work with huge impact.

Prasad Rao

Through my blogs, I strive to highlight not just the “what” of new services, but also the “why” and “how” they can transform businesses and user experiences. As a solutions architect specializing in Microsoft Workloads on AWS, I help customers migrate and modernize their workloads and build scalable architecture on AWS. I also mentor diverse people to excel in their cloud careers.

Elizabeth Fuentes

Every time I start writing a new blog, I feel honored to be part of this team, to be able to experiment with something new before it’s released, and to be able to share my experience with the reader. This team is made up of specialists of all levels and from multiple countries and together, we are a multicultural and multi-specialty team. Thank you, reader, for being here.

Betty Zheng (郑予彬)

Joining the News Blog team has transformed how I communicate about technology. With an ever-curious mindset, I approach each new announcement aiming to make innovative services accessible and engaging. By bringing my unique and diverse perspective to technical content, I strive to help developers truly enjoy exploring our latest technologies.

Micah Walter

As a senior solutions architect, I support enterprise customers in the New York City region and beyond. I advise executives, engineers, and architects at every step along their journey to the cloud, with a deep focus on sustainability and practical design.

I also want to give credit to our behind-the-scenes editor-in-chief, Jane Watson, and program manager, Jane Scolieri, who play an essential role in helping us get product launch news to you as soon as it happens, including the 60 launches we announced in one week at re:Invent 2024!

Share your feedback
At AWS, we are customer obsessed. We’re always focused on improving and providing a better customer experience, and we need your feedback to do so. Take our survey to share insights about your experience with the AWS News Blog and suggestion for how we can serve you even better.

This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.

Channy

Accelerate operational analytics with Amazon Q Developer in Amazon OpenSearch Service

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/accelerate-operational-analytics-with-amazon-q-developer-in-amazon-opensearch-service/

Today, I’m happy to announce Amazon Q Developer support for Amazon OpenSearch Service, providing AI-assisted capabilities to help you investigate and visualize operational data. Amazon Q Developer enhances the OpenSearch Service experience by reducing the learning curve for query languages, visualization tools, and alerting features. The new capabilities complement existing dashboards and visualizations by enabling natural language exploration and pattern detection. After incidents, you can rapidly create additional visualizations to strengthen your monitoring infrastructure. This enhanced workflow accelerates incident resolution and optimizes engineering resource usage, helping you focus more time on innovation rather than troubleshooting.

Amazon Q Developer in Amazon OpenSearch Service improves operational analytics by integrating natural language exploration and generative AI capabilities directly into OpenSearch workflows. During incident response, you can now quickly gain context on alerts and log data, leading to faster analysis and resolution times. When alert monitors trigger, Amazon Q Developer provides summaries and insights directly in the alerts interface, helping you understand the situation quickly without waiting for specialists or consulting documentation. From there, you can use Amazon Q Developer to explore the underlying data, build visualizations using natural language, and identify patterns to determine root causes. For example, you can create visualizations that break down errors by dimensions such as Region, data center, or endpoint. Additionally, Amazon Q Developer assists with dashboard configuration and recommends anomaly detectors for proactive alerting, improving both initial monitoring setup and troubleshooting efficiency.

Get started with Amazon Q Developer in OpenSearch Service
To get started, I go to my OpenSearch user interface and sign in. From the home page, I choose a workspace to test Amazon Q Developer in OpenSearch Service. For this demonstration, I use a preconfigured environment with the sample logs dataset available on the user interface.

This feature is on by default through the Amazon Q Developer Free tier, which is also on by default. You can disable the feature by unselecting the Enable natural language query generation checkbox under the Artificial Intelligence (AI) and Machine Learning (ML) section during domain creation or by editing the cluster configuration in console.

In OpenSearch Dashboards, I navigate to Discover from the left navigation pane. To use natural language to explore the data, I switch to PPL language in order to show the prompt box.

I choose the Amazon Q icon in the main navigation bar to open the Amazon Q panel. You can use this panel to create recommended anomaly detectors to drive alerting and use natural language to generate visualization.

I enter the following prompt in the Ask a natural language question text box:

Show me a breakdown of HTTP response codes for the last 24 hours

When results appear, Amazon Q automatically generates a summary of these results. You can control the summary display using the Show result summarization option under the Amazon Q panel to hide or show the summary. You can use the thumbs up or thumbs down buttons to provide feedback, and you can copy the summary to your clipboard using the copy button.

Other capabilities of Amazon Q Developer in OpenSearch Service are generating visualizations directly from natural language descriptions, providing conversational assistance for OpenSearch related queries, providing AI-generated summaries and insights for your OpenSearch alerts, and analyzing your data, and suggesting appropriate anomaly detectors.

Let’s look into how to generate visualizations directly from natural language descriptions. I choose Generate visualization from Amazon Q panel. I enter Create a bar chart showing the number of requests by HTTP status code in the input field and choose generate.

To refine the visualization, you can choose Edit visual and add style instructions such as Show me a pie chart or Use a light gray background with a white grid.

Now available
You can now use Amazon Q Developer in OpenSearch Service to reduce mean time to resolution, enable more self-service troubleshooting, and help teams extract greater value from your observability data.

The service is available today in US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai), Asia Pacific (Sydney), Asia Pacific (Tokyo), Canada (Central), Europe (Frankfurt), Europe (London), Europe (Paris), and South America (São Paulo) AWS Regions.

To learn more, visit the Amazon Q Developer documentation and start using Amazon Q Developer in your OpenSearch Service domain today.

— Esra


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Amazon API Gateway now supports dual-stack (IPv4 and IPv6) endpoints

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/amazon-api-gateway-now-supports-dual-stack-ipv4-and-ipv6-endpoints/

Today, we are launching IPv6 support for Amazon API Gateway across all endpoint types, custom domains, and management APIs, in all commercial and AWS GovCloud (US) Regions. You can now configure REST, HTTP, and WebSocket APIs, and custom domains, to accept calls from IPv6 clients alongside the existing IPv4 support. You can also call API Gateway management APIs from dual-stack (IPv6 and IPv4) clients. As organizations globally confront growing IPv4 address scarcity and increasing costs, implementing IPv6 becomes critical for future-proofing network infrastructure. This dual-stack approach helps organizations maintain future network compatibility and expand global reach. To learn more about dualstack in the Amazon Web Services (AWS) environment, see the IPv6 on AWS documentation.

Creating new dual-stack resources

This post focuses on two ways to create an API or a domain name with a dualstack IP address type: AWS Management Console and AWS Cloud Development Kit (CDK).

AWS Console

When creating a new API or domain name in the console, select IPv4 only or dualstack (IPv4 and IPv6) for the IP address type.

As shown in the following image, you can select the dualstack option when creating a new REST API.
For custom domain names, you can similarly configure dualstack as shown in the next image.

If you need to revert to IPv4-only for any reason, you can modify the IP address type setting, with no need to redeploy your API for the update to take effect.

REST APIs of all endpoint types (EDGE, REGIONAL and PRIVATE) support dualstack. Private REST APIs only support dualstack configuration.

AWS CDK

With AWS CDK, start by configuring a dual-stack REST API and domain name.

const api = new apigateway.RestApi(this, "Api", {
  restApiName: "MyDualStackAPI",
  endpointConfiguration: {ipAddressType: "dualstack"}
});

const domain_name = new apigateway.DomainName(this, "DomainName", {
  regionalCertificateArn: 'arn:aws:acm:us-east-1:111122223333:certificate/a1b2c3d4-5678-90ab',
  domainName: 'dualstack.example.com',
  endpointConfiguration: {
    types: ['Regional'],
    ipAddressType: 'dualstack'
  },
  securityPolicy: 'TLS_1_2'
});

const basepathmapping = new apigateway.BasePathMapping(this, "BasePathMapping", {
  domainName: domain_name,
  restApi: api
});

IPv6 Source IP and authorization

When your API begins receiving IPv6 traffic, client source IPs will be in IPv6 format. If you use resource policies, Lambda authorizers, or AWS Identity and Access Management (IAM) policies that reference source IP addresses, make sure they’re updated to accommodate IPv6 address formats.

For example, to permit traffic from a specific IPv6 range in a resource policy.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": "*",
      "Action": "execute-api:Invoke",
      "Resource": "execute-api:stage-name/*",
      "Condition": {
        "IpAddress": {
          "aws:SourceIp": [
            "192.0.2.0/24",
            "2001:db8:1234::/48"
          ]
        }
      }
    }
  ]
}

Summary

API Gateway dual-stack support helps manage IPv4 address scarcity and costs, comply with government and industry mandates, and prepare for the future of networking. The dualstack implementation provides a smooth transition path by supporting both IPv4 and IPv6 clients simultaneously.

To get started with API Gateway dual-stack support, visit the Amazon API Gateway documentation. You can configure dualstack for new APIs or update existing APIs with minimal configuration changes.

Betty

Special thanks to Ellie Frank (elliesf), Anjali Gola (anjaligl), and Pranika Kakkar (pranika) for providing resources, answering questions, and offering valuable feedback during the writing process. This blog post was made possible through the collaborative support of the service and product management teams.


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Accelerating CI with AWS CodeBuild: Parallel test execution now available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/accelerating-ci-with-aws-codebuild-parallel-test-execution-now-available/

I’m excited to announce that AWS CodeBuild now supports parallel test execution, so you can run your test suites concurrently and reduce build times significantly.

With the demo project I wrote for this post, the total test time went down from 35 minutes to six minutes, including the time to provision the environments. These two screenshots from the AWS Management Console show the difference.

Sequential execution of the test suite

CodeBuild Parallel Test Results

Parallel execution of the test suite

CodeBuild Parallel Test Results

Very long test times pose a significant challenge when running continuous integration (CI) at scale. As projects grow in complexity and team size, the time required to execute comprehensive test suites can increase dramatically, leading to extended pipeline execution times. This not only delays the delivery of new features and bug fixes, but also hampers developer productivity by forcing them to wait for build results before proceeding with their tasks. I have experienced pipelines that took up to 60 minutes to run, only to fail at the last step, requiring a complete rerun and further delays. These lengthy cycles can erode developer trust in the CI process, contribute to frustration, and ultimately slow down the entire software delivery cycle. Moreover, long-running tests can lead to resource contention, increased costs because of wasted computing power, and reduced overall efficiency of the development process.

With parallel test execution in CodeBuild, you can now run your tests concurrently across multiple build compute environments. This feature implements a sharding approach where each build node independently executes a subset of your test suite. CodeBuild provides environment variables that identify the current node number and the total number of nodes, which are used to determine which tests each node should run. There is no control build node or coordination between nodes at build time—each node operates independently to execute its assigned portion of your tests.

To enable test splitting, configure the batch fanout section in your buildspec.xml, specifying the desired parallelism level and other relevant parameters. Additionally, use the codebuild-tests-run utility in your build step, along with the appropriate test commands and the chosen splitting method.

The tests are split based on the sharding strategy you specify. codebuild-tests-run offers two sharding strategies:

  • Equal-distribution. This strategy sorts test files alphabetically and distributes them in chunks equally across parallel test environments. Changes in the names or quantity of test files might reassign files across shards.
  • Stability. This strategy fixes the distribution of tests across shards by using a consistent hashing algorithm. It maintains existing file-to-shard assignments when new files are added or removed.

CodeBuild supports automatic merging of test reports when running tests in parallel. With automatic test report merging, CodeBuild consolidates tests reports into a single test summary, simplifying result analysis. The merged report includes aggregated pass/fail statuses, test durations, and failure details, reducing the need for manual report processing. You can view the merged results in the CodeBuild console, retrieve them using the AWS Command Line Interface (AWS CLI), or integrate them with other reporting tools to streamline test analysis.

Let’s look at how it works
Let me demonstrate how to implement parallel testing in a project. For this demo, I created a very basic Python project with hundreds of tests. To speed things up, I asked Amazon Q Developer on the command line to create a project and 1,800 test cases. Each test case is in a separate file and takes one second to complete. Running all tests in a sequence requires 30 minutes, excluding the time to provision the environment.

In this demo, I run the test suite on ten compute environments in parallel and measure how long it takes to run the suite.

To do so, I added a buildspec.yml file to my project.

version: 0.2

batch:
  fast-fail: false
  build-fanout:
    parallelism: 10 # ten runtime environments 
    ignore-failure: false

phases:
  install:
    commands:
      - echo 'Installing Python dependencies'
      - dnf install -y python3 python3-pip
      - pip3 install --upgrade pip
      - pip3 install pytest
  build:
    commands:
      - echo 'Running Python Tests'
      - |
         codebuild-tests-run \
          --test-command 'python -m pytest --junitxml=report/test_report.xml' \
          --files-search "codebuild-glob-search 'tests/test_*.py'" \
          --sharding-strategy 'equal-distribution'
  post_build:
    commands:
      - echo "Test execution completed"

reports:
  pytest_reports:
    files:
      - "*.xml"
    base-directory: "report"
    file-format: JUNITXML 

There are three parts to highlight in the YAML file.

First, there’s a build-fanout section under batch. The parallelism command tells CodeBuild how many test environments to run in parallel. The ignore-failure command indicates if failure in any of the fanout build tasks can be ignored.

Second, I use the pre-installed codebuild-tests-run command to run my tests.

This command receives the complete list of test files and decides which of the tests must be run on the current node.

  • Use the sharding-strategy argument to choose between equally distributed or stable distribution as I explain above.
  • Use the files-search argument to pass all the files that are candidates for a run. We recommend to use the provided codebuild-glob-search command for performance reasons, but any file search tool, such as find(1), will work.
  • I pass the actual test command to run on the shard with the test-command argument.

Lastly, the reports section instructs CodeBuild to collect and merge the test reports on each node.

Then, I open the CodeBuild console to create a project and a batch build configuration for this project. There’s nothing new here, so I’ll spare you the details. The documentation has all the details to get you startedParallel testing works on batch builds. Make sure to configure your project to run in batch.

CodeBuild : create a batch build

Now, I’m ready to trigger an execution of the test suite. I can commit new code on my GitHub repository or trigger the build in the console.

CodeBuild : trigger a new build

After a few minutes, I see a status report of the different steps of the build; with a status for each test environment or shard.

CodeBuild: status

When the test is complete, I select the Reports tab to access the merged test reports.

CodeBuild: test reports

The Reports section aggregates all test data from all shards and keeps the history for all builds. I select my most recent build in the Report history section to access the detailed report.

CodeBuild: Test Report

As expected, I can see the aggregated and the individual status for each of my 1,800 test cases. In this demo, they’re all passing, and the report is green.

The 1,800 tests of the demo project take one second each to complete. When I run this test suite sequentially, it took 35 minutes to complete. When I run the test suite in parallel on ten compute environments, it took six minutes to complete, including the time to provision the environments. The parallel run took 17.1 percent of the time of the sequential run. Actual numbers will vary with your projects.

Additional things to know
This new capability is compatible with all testing frameworks. The documentation includes examples for Django, Elixir, Go, Java (Maven), Javascript (Jest), Kotlin, PHPUnit, Pytest, Ruby (Cucumber), and Ruby (RSpec).

For test frameworks that don’t accept space-separated lists, the codebuild-tests-run CLI provides a flexible alternative through the CODEBUILD_CURRENT_SHARD_FILES environment variable. This variable contains a newline-separated list of test file paths for the current build shard. You can use it to adapt to different test framework requirements and format test file names.

You can further customize how tests are split across environments by writing your own sharding script and using the CODEBUILD_BATCH_BUILD_IDENTIFIER environment variable, which is automatically set in each build. You can use this technique to implement framework-specific parallelization or optimization.

Pricing and availability
With parallel test execution, you can now complete your test suites in a fraction of the time previously required, accelerating your development cycle and improving your team’s productivity. The demo project I created to illustrate this post consumes 18.7 percent of the time of a sequential build.

Parallel test execution is available on all three compute modes offered by CodeBuild: on-demand, reserved capacity, and AWS Lambda compute.

This capability is available today in all AWS Regions where CodeBuild is offered, with no additional cost beyond the standard CodeBuild pricing for the compute resources used.

I invite you to try parallel test execution in CodeBuild today. Visit the AWS CodeBuild documentation to learn more and get started with parallelizing your tests.

— seb

PS: Here’s the prompt I used to create the demo application and its test suite: “I’m writing a blog post to announce codebuild parallel testing. Write a very simple python app that has hundreds of tests, each test in a separate test file. Each test takes one second to complete.”


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Firewall support for AWS Amplify hosted sites

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/firewall-support-for-aws-amplify-hosted-sites/

Today, we’re announcing the general availability of the AWS WAF integration with AWS Amplify Hosting.

Web application owners are constantly working to protect their applications from a variety of threats. Previously, if you wanted to implement a robust security posture for your Amplify Hosted applications, you needed to create architectures using Amazon CloudFront distributions with AWS WAF protection, which required additional configuration steps, expertise, and management overhead.

With the general availability of AWS WAF in Amplify Hosting, you can now directly attach a web application firewall to your AWS Amplify apps through a one-click integration in the Amplify console or using infrastructure as code (IaC). This integration gives you access to the full range of AWS WAF capabilities including managed rules, which provide protection against common web exploits and vulnerabilities like SQL injection and cross-site scripting (XSS). You can also create your own custom rules based on your specific application needs.

This new capability helps you implement defense-in-depth security strategies for your web applications. You can take advantage of AWS WAF rate-based rules to protect against distributed denial of service (DDoS) attacks by limiting the rate of requests from IP addresses. Additionally, you can implement geo-blocking to restrict access to your applications from specific countries, which is particularly valuable if your service is designed for specific geographic regions.

Let’s see how it works
Setting up AWS WAF protection for your Amplify app is straightforward. From the Amplify console, navigate to your app settings, select the Firewall tab, and choose the predefined rules you want to apply to your configuration. AWS WAF integration in AWS Amplify Hosting

Amplify hosting simplifies configuring firewall rules. You can activate four categories of protection.

  • Amplify-recommended firewall protection – Protect against the most common vulnerabilities found in web applications, block IP addresses from potential threats based on Amazon internal threat intelligence, and protect against malicious actors discovering application vulnerabilities.
  • Restrict access to amplifyapp.com – Restrict access to the default Amplify generated amplifyapp.com domain. This is useful when you add a custom domain to prevent bots and search engines from crawling the domain.
  • Enable IP address protection – Restrict web traffic by allowing or blocking requests from specified IP address ranges.
  • Enable country protection – Restrict access based on specific countries.

Protections enabled through the Amplify console will create an underlying web access control list (ACL) in your AWS account. For fine-grained rulesets, you can use the AWS WAF console rule builder.

After a few minutes, the rules are associated to your app and AWS WAF blocks suspicious requests.

If you want to see AWS WAF in action, you can simulate an attack and monitor it using the AWS WAF request inspection capabilities. For example, you can send a request with an empty User-Agent value. It will trigger a blocking rule in AWS WAF.

Let’s first send a valid request to my app.

curl -v -H "User-Agent: MyUserAgent" https://main.d3sk5bt8rx6f9y.amplifyapp.com/
* Host main.d3sk5bt8rx6f9y.amplifyapp.com:443 was resolved.
...(redacted for brevity)...
> GET / HTTP/2
> Host: main.d3sk5bt8rx6f9y.amplifyapp.com
> Accept: */*
> User-Agent: MyUserAgent
> 
* Request completely sent off
< HTTP/2 200 
< content-type: text/html
< content-length: 0
< date: Mon, 10 Mar 2025 14:45:26 GMT
 

We can observe that the server returned an HTTP 200 (OK) message.

Then, send a request with no value associated to the User-Agent HTTP header.

 curl -v -H "User-Agent: " https://main.d3sk5bt8rx6f9y.amplifyapp.com/ 
* Host main.d3sk5bt8rx6f9y.amplifyapp.com:443 was resolved.
... (redacted for brevity) ...
> GET / HTTP/2
> Host: main.d3sk5bt8rx6f9y.amplifyapp.com
> Accept: */*
> 
* Request completely sent off
< HTTP/2 403 
< server: CloudFront
... (redacted for brevity) ...
<TITLE>ERROR: The request could not be satisfied</TITLE>
</HEAD><BODY>
<H1>403 ERROR</H1>
<H2>The request could not be satisfied.</H2>

We can observe that the server returned an HTTP 403 (Forbidden) message.

AWS WAF provide visibility into request patterns, helping you fine-tune your security settings over time. You can access logs through Amplify Hosting or the AWS WAF console to analyze traffic trends and refine security rules as needed.

AWS WAF integration in AWS Amplify Hosting - Dashboard

Availability and pricing
Firewall support is available in all AWS Regions in which Amplify Hosting operates. This integration falls under an AWS WAF global resource, similar to Amazon CloudFront. Web ACLs can be attached to multiple Amplify Hosting apps, but they must reside in the same Region.

The pricing for this integration follows the standard AWS WAF pricing model, You pay for the AWS WAF resources you use based on the number of web ACLs, rules, and requests. On top of that, AWS Amplify Hosting adds $15/month when you attach a web application firewall to your application. This is prorated by the hour.

This new capability brings enterprise-grade security features to all Amplify Hosting customers, from individual developers to large enterprises. You can now build, host, and protect your web applications within the same service, reducing the complexity of your architecture and streamlining your security management.

To learn more, visit the AWS WAF integration documentation for Amplify or try it directly in the Amplify console.

— seb


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Detailed geographic information for all AWS Regions and Availability Zones is now available

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/now-available-geography-information-for-all-aws-regions-and-availability-zones/

Starting today, you can get more granular visibility of geographic location information for AWS Regions and AWS Availability Zones (AZs). This detailed information will help you choose the Regions and AZs that align with your regulatory, compliance, and operational requirements.

We continue to expand the AWS global infrastructure to meet your business requirements and now have 114 AZs across 36 Regions. We have announced plans to add 12 more AZs and four Regions in New Zealand, Kingdom of Saudi Arabia, Taiwan, and the AWS European Sovereign Cloud.

One of the things we’ve learned from our customers is the need to have more visibility into the specific location of infrastructure within an AWS Region. This is important for customers in highly regulated industries such as the financial industry or gaming, where there are specific requirements for the physical placement of infrastructure. For example, FanDuel, a leading sports gaming company based in the U.S., is scaling into new markets across the U.S. and Canada. They are taking advantage of the improved geographic transparency to make more informed decisions and ensure they’re meeting data residency requirements as they scale their business quickly.

Geographies for AWS Regions
To find the geographic information for your Region, you can visit the AWS Global Infrastructure Regions and Availability Zones page. Once you navigate to this page, you can choose any tab on the map and scroll to the bottom to review the geographic information for each Region. See the following image for an example showing the North America Regions. As would be expected, the infrastructure for the US West (Oregon) Region is located in the United States of America, and the Canada (Central) Region is located in Canada.

Geographies for Availability Zones
To find the specific geographic information for an AZ, you can visit the AWS Regions and Availability Zones page in AWS Documentation. Choose the Region you’re interested in and you’ll find a table showing you the geography for that Region. As you see in the following screenshot, the infrastructure of the AZ with AZ ID use1-az1 is located in Virginia, United States of America.

Geographies_AZs

Stay tuned
We will update these pages to reflect new geographic information as we continue to grow our AWS Global infrastructure footprint and add more AWS Regions and AZs.

Quick links
To learn more, visit the AWS Global Infrastructure Regions and Availability Zones page or AWS Regions and Availability Zones in AWS Documentation, and send feedback to AWS re:Post or through your usual AWS Support contacts.

Prasad


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Disaster Recovery 101: Improving RTO and RPO Goals with the Cloud

Post Syndicated from Kari Rivas original https://www.backblaze.com/blog/disaster-recovery-101-improving-rto-and-rpo-goals-with-the-cloud/

A decorative image showing various towers and a cloud.

Creating clear goals is inevitably part of any business strategy. You’ve likely heard of the acronym SMART—specific, measurable, actionable, realistic, and time-bound—when it comes to goal setting. As a business leader in information technology or a related business unit, you’re responsible for developing sound goals for business technology, data protection, and disaster recovery. 

Two key metrics that feed into those strategies are your recovery time objective (RTO) and recovery point objective (RPO). Like all the other goals your business sets, the RTO and RPO should also be SMART goals. 

So, how can you set meaningful RTO and RPO objectives for your business? And how can the cloud help you achieve or improve on those objectives? Today I’ll talk about how to smarten up these objectives to lead to better business continuity (BC) and a more effective disaster recovery (DR) plan.

The Essential Guide to Disaster Recovery Planning

Read more about how to build a disaster recovery plan for your organization.

Get the Disaster Recovery Ebook ➔ 

Why do RTO and RPO matter?

RTO and RPO are two fundamental inputs to a comprehensive disaster recovery plan. They also very much guide how you’ll structure your backup strategy and engineer your backup architecture.

RTO is a business metric that states the maximum length of time a business can tolerate for recovery. It’s important to note the difference between recovery and restoration of data here. Restoring data is just one part of a recovery. 

Recovery means systems are back up and running—fully functional—with users (employees, customers, etc.) able to utilize them in the same manner as before the data incident occurred.

RPO measures the maximum amount of data a company can afford to lose (or is willing to lose), measured in units of time. For instance, an RPO of 12 hours means that the company can accept the risk (financial risk, risk to the brand, etc.) of having lost 12 hours worth of data. So, if you run backups every 11 hours, you will be able to meet your RPO.

How to set RTO and RPO

Creating these objectives is a business decision—not an IT decision. If you’re an IT leader, your job is to work with your internal stakeholders to fully understand the business and the criticality of various applications and services in order to help define the RTO and RPO. 

Put another way: The decision about what standard to meet is a shared responsibility. And those standards (recovery time, file durability, etc.) are the targets that IT and infrastructure providers teams must meet. 

RTO and RPO may be different from one system to another. Some applications are more important than others. 

Keep in mind that it’s likely that department heads will all say their services are the most important to immediately recover. But if everything is deemed critical, then nothing is. 

Discuss how data loss and time to recovery impact the business in quantifiable details—revenue lost, number of customers affected, etc.—in order to truly prioritize systems and set appropriate RTOs and RPOs.

Making your RTOs and RPOs SMART

Remember that your objectives should be SMART:

  • Specific: Think through how granular your RTOs and RPOs should be. In addition to different RTOs and RPOs per application, you may also need different RTOs and RPOs per scenario. For example, the RTO for a ransomware attack is much different than that for hardware failure.
  • Measurable: One good way of measuring the efficacy of your RTOs and RPOs is by conducting DR testing. Run fire drills and conduct tabletop exercises. Practice restoring data. These inputs will help you understand if your objectives are meaningful and obtainable.
  • Actionable: Document your RTO and RPO in your DR plans and ensure they align with any business continuity risk management plans or goals around maximum allowable risk tolerance. You may also want to document the assumptions and inputs that formed the RTO and RPO. For instance, how much revenue is lost when a given system is down? Explain how that factor drives your RTO. 
  • Realistic: Don’t let your stakeholders set unachievable objectives. If there is an ask for a very low RTO and/or RPO, help your stakeholder understand exactly what it will take—and how much it will cost—to implement that objective.
  • Time-bound: The RTO can be defined in seconds up to weeks. The shorter the RTO, the more expensive the investment will be to meet it. 

Remember that you’re always balancing RTO and RPO against an unachievable “perfect” state. For instance, you would likely need multiple failover hot sites with replicated data to meet an RTO of seconds of downtime. 

RTO is a forward-looking measurement; RPO is a backward-looking measurement that essentially represents the frequency of your backups. 

A short RPO means more recent backup data is needed, and, yes, that also means greater investment. RPOs measured in seconds may require high-speed backup technology like continuous replication.

How to discuss RTO and RPO with business leaders

Discussing technical concepts with internal stakeholders can be challenging. To guide the objective-setting discussion with stakeholders, use the following questions as a guide:

  1. Where and how do you store data? 
  2. How often does your data change?
  3. What would a minute of downtime cost your department, in terms of revenue, risk, loss of productivity, impact to customers, etc.?
  4. What are the compliance or industry requirements for maintaining sensitive data?
  5. Do you have a way of manually transacting business if service is down? 

Your IT department may already be well aware of many of these goals, but it’s good to do a fresh and full inventory of data and data management procedures. For example, even with the rise of shared drives, many employees still save important data locally. Or, there may be business-critical data being saved in services like Microsoft 365 or Kubernetes—and those services are often not adequately backed up.

How do RTO and RPO affect backup strategy?

Your RPO is often more directly related to backup strategy, although RTO certainly informs backup strategy. If you need a very low RPO (i.e., the business can tolerate very little data loss), you must plan to run backups more frequently. This ensures you always have very recent data to recover. 

RTO, however, relates more to systems and infrastructure—again, because the objective is about recovery and not just restoring data. RTO will drive investment decisions around backup and DR architecture.

Your backup strategy or tech stack should not dictate either your RTO or your RPO. 

First, you should define your RTO and RPO, and then you must determine if changes in backup policy are needed or if you need to update any backup systems in order to reach desired RTOs and RPOs. 

Your RTO will drive decisions around backup and DR infrastructure; your RPO will drive decisions around frequency of backup and type of backup.

How does the cloud help companies meet RTO and RPO goals?

Using a public cloud for backup and archive can help you achieve your desired RTO and/or RPO. An obvious example is using cloud to replace LTO tape backup. Tape backup has some of the worst (maybe the worst) RTOs and RPOs. It takes an extraordinarily long time to recover from tape, and backups are likely not as frequent as they should be because tape is often not properly maintained. Migrating your tape backups to a public cloud like Backblaze B2 Cloud Storage is still cost-effective and it will drastically improve RTO and RPO.

If you’re using a hyperscaler like AWS, you may have had to cut back on frequency of backup or needed retention periods due to exorbitant fees. Shifting your backups to Backblaze B2 can help you achieve your goals: Backblaze B2 is one-fifth the cost of AWS S3, you can afford to run and save more frequent backups, thus lowering your overall RPO.

Replication is another technology that can help reduce RTOs. Many enterprise businesses will already have a failover site, but keeping an extra copy of your data in the cloud ensures you can still meet your desired RTO in the case of a DR site or production facility takeout. This is exactly what brought SaaS platform Centerbase to Backblaze.

More commonly, if it’s inordinately expensive to own your own DR site, you can store your backups in Backblaze B2 and utilize Cloud Replication for added redundancy.

RTO and RPO and your business

Ultimately, you should frame your RTO and RPO in terms of business impact. Then, reverse engineer your backup and DR infrastructure to support those objectives. Next, identify the storage systems for your data based on its business criticality and desired RTO and RPO. 

Depending on your business goals, you’ll likely use cloud storage services, on-premises storage, or some combination of the two. Regardless of the type of business you run, demonstrating that you have an airtight DR plan with SMART RTO and RPO goals will instill confidence in your business partners, help with cyber insurance eligibility, and shore up your organization’s ability to withstand data disasters.

The post Disaster Recovery 101: Improving RTO and RPO Goals with the Cloud appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

DR 101: Assembling Your Incident Response Team

Post Syndicated from Kari Rivas original https://www.backblaze.com/blog/dr-101-assembling-your-incident-response-team/

A decorative image showing a computer screen with several profiles and a cloud.

A well-defined disaster recovery (DR) plan relies heavily on a coordinated incident response team. Think of your incident response team like a pit crew. It’s easy to assume you’ll have a good race when everything is performing smoothly, but the real test comes when something goes wrong—maybe a tire blows or the engine overheats. In those moments, success isn’t about having the best tools in the garage; it’s about having the right team, working together, to quickly solve problems and get back on track.

When your team is facing a disaster recovery scenario, whether it’s a cyber attack, natural disaster, outage, or data breach, the speed and coordination of your team determines how quickly and how well you can move forward. In this post, I’m breaking down how to assemble a team that can respond with precision, minimize downtime, and keep your organization running smoothly when unexpected issues arise.

Establishing key team members, roles, and hierarchy

The incident response team (IRT) is the backbone of your DR response and is responsible for leading the recovery efforts during a disaster. Here’s a breakdown of possible key IRT roles:

  • Incident commander: Oversees the entire incident response process, making critical decisions and delegating tasks to team members.
  • Technical lead: Provides technical expertise, directing recovery efforts for IT infrastructure and data restoration.
  • Communications lead: Handles external and internal communication, ensuring timely updates for stakeholders and mitigating potential reputational damage.
  • Documentation lead: Maintains the DR runbook, ensuring its accuracy and updating it with post-incident findings.
  • Legal counsel: Provides legal guidance and ensures compliance with relevant regulations during the response and recovery process.

Building redundancy

Building redundancy in your IRT allows you to account for team member absences. This includes IT leadership; don’t assume you’ll be in the office when a disaster happens. Assign backup personnel for critical roles within the team to ensure continuity in the event of unforeseen circumstances.

Establish a clear succession plan for leadership roles within the IRT. This ensures a smooth transition if the primary incident commander or other key personnel become unavailable during a disaster.

Establishing a reporting hierarchy

Clearly define a reporting hierarchy within the IRT, outlining who reports to whom and the escalation process for making critical decisions. A clear chain of command during a crisis prevents confusion and delays that could result in prolonged downtime and increased risks.

The importance of clear communication

A critical component of any DR plan is clear communication to employees and executives regarding their specific roles during a security incident. This ensures that the assigned team leader can coordinate a unified response. Remember to include guidelines about incident escalation, as well as agreed-upon methods of communication (e.g., email, direct messaging, video calls, etc.).

Executive sponsorship: Beyond awareness

Executive buy-in is paramount for a successful DR strategy. While awareness of the impact of ransomware attacks has grown over the years, contextualizing DR plans with historical financial impacts, downtime implications, and reputational risk associated with such attacks can help to communicate why DR is a top-line priority.

Tip: Educating executives

Framing the DR plan in terms of cost avoidance, user downtime minimization, and reputational risk mitigation can resonate better with executives. Quantify the potential financial losses from data breaches and system outages to garner executive support for DR initiatives.

Beyond cell phones: Communication channels

Disasters can disrupt traditional communication methods like cell phone service. Develop alternative communication channels for the IRT, such as designated email threads, satellite phones, or pre-arranged conference call bridges. It is imperative to include this information and contact details in your DR runbook for immediate accessibility during crises.

By establishing a well-defined team structure with clear roles, communication protocols, and redundancy measures, enterprise businesses can ensure a coordinated and efficient response to data disasters. 

A well-prepared team leads to a resilient recovery

Your DR strategy is only as effective as the team behind it. By defining clear roles, building in redundancy, and establishing a reporting hierarchy, IT leaders can eliminate confusion and accelerate recovery efforts. Moreover, securing executive sponsorship and ensuring clear communication strengthens your ability to respond effectively. DR isn’t just about the plan on paper. It’s about how you execute that plan and set your team up for success. 

The post DR 101: Assembling Your Incident Response Team appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Backblaze and CHESA: Doubling Down on a Premier Media Workflow Partnership

Post Syndicated from Mary Ellen Cavanagh original https://www.backblaze.com/blog/backblaze-and-chesa-partnership/

A decorative image showing the Backblaze and CHESA logos.

Media workflows have always been complex, requiring seamless collaboration, robust storage, and advanced systems integration. Today, with the explosion of content demands and rapid technological advancements, media organizations need solutions that can scale, innovate, and empower teams to deliver faster and better. 

Backblaze and CHESA, long-standing partners and leaders in media workflow solutions, are doubling down on their relationship with CHESA to elevate creative workflows with a joint go-to-market partnership. This enhanced partnership builds on years of success, combining Backblaze’s high-performance, secure cloud storage with CHESA’s expertise in media technology systems integration to provide even more impactful solutions tailored to the needs of modern media-driven organizations.

Together, we’re continuing to make it easier than ever for organizations to streamline content production, enhance accessibility, and achieve business objectives with greater efficiency. In this blog, I’ll explain the key benefits of this expanded collaboration and highlight how it’s already driving transformative results for clients like the Philadelphia Eagles.

The media workflow challenge

From production studios and broadcasters to professional sports teams and creative agencies, media organizations face a growing list of challenges:

  • Massive data volumes: Video, audio, and other rich media assets require scalable and secure storage solutions to handle terabytes or even petabytes of data.
  • Fragmented workflows: Teams often juggle multiple tools and platforms, leading to inefficiencies and bottlenecks.
  • Access and collaboration: Remote work and distributed teams demand seamless real-time access to media assets.
  • Budget constraints: Organizations need cost-effective solutions that don’t compromise performance or security.

The expanded partnership between Backblaze and CHESA continues to address these pain points head-on by combining best-in-class cloud storage with tailored workflow solutions.

The Backblaze + CHESA solution

Real-world success: The Philadelphia Eagles

One of the most compelling examples of the Backblaze + CHESA partnership is the Philadelphia Eagles’ transition from traditional LTO tape storage to a cloud-based media workflow. With over 800TB under management, switching to cloud storage meant that the team instantly made their data more agile, scoring immediate access to faster content creation and remote workflows. 

“Now I can easily share entire broadcasts by copying and sharing a link from our MAM. No need for FTP downloads or uploading to other platforms. It’s fast, seamless, and ensures everyone can view the content without issues.”
—Stacy Kelleher, Director of Production, Philadelphia Eagles

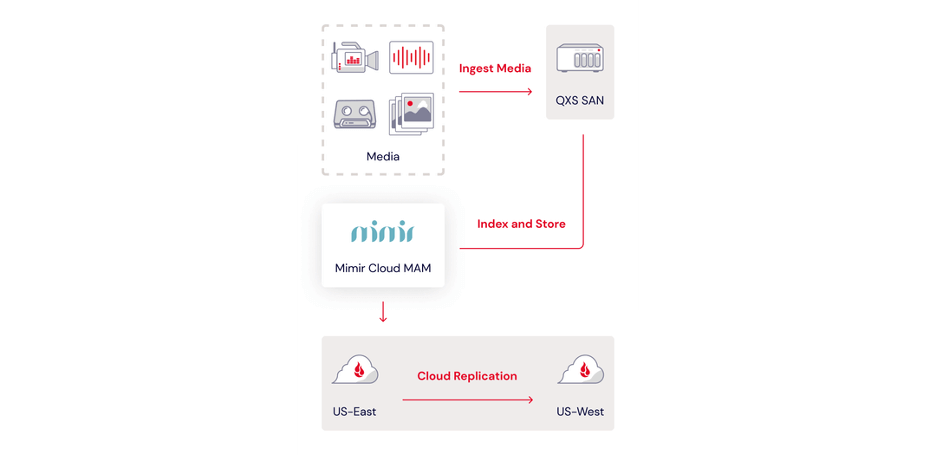
Backblaze B2 integrated seamlessly with the Eagles’ preferred tech stack, which leverages a Quantum QXS storage area network (SAN) and Mimir, a cloud-based video production platform.

The challenge

The Eagles faced significant challenges with their legacy storage system:

  • Limited accessibility: LTO tape storage made it difficult to access archived footage, which hindered content production timelines quickly.
  • Time-consuming processes: Retrieving footage from physical tapes was manual and slow.
  • Scaling limitations: As the team’s content library grew, so did the complexity and cost of managing tape storage.

The solution

By leveraging the expanded capabilities of Backblaze and CHESA’s partnership, the Eagles:

  • Transitioned their extensive media library to Backblaze B2 Cloud Storage.
  • Integrated CHESA’s tailored media workflow solutions for seamless access and collaboration.
  • Gained immediate access to decades of archived footage, enabling faster content creation and improved fan engagement.

The results

The Eagles’ media team now enjoys:

  • Accelerated content production: Instant access to archived footage has streamlined workflows, allowing the team to create engaging content more efficiently.
  • Enhanced scalability: With Backblaze B2, the Eagles can easily scale their storage as their content library grows.
  • Improved fan engagement: Faster production timelines enable the team to deliver high-quality content that keeps fans connected and engaged.

Peripheral content drives revenue through monetized clicks like highlights and select moments. Quick sharing and streamlined proof-of-performance delivery keep sponsors satisfied.”
—Ryan Lakey, Principal Lead, Solutions, CHESA

Accelerated media workflows

Integrating Backblaze B2 Cloud Storage with CHESA’s media workflow expertise has long been a cornerstone of success for media teams. By enhancing this integration, media teams can experience even faster workflows, immediate asset access, and seamless collaboration across tools and teams. By eliminating the delays associated with traditional storage methods, teams can:

  • Quickly retrieve and edit high-resolution media files.
  • Share assets effortlessly with collaborators anywhere in the world.
  • Spend less time managing infrastructure and more time creating impactful content.

Backblaze + CHESA benefits

Scalable and cost-effective storage

Backblaze B2 Cloud Storage offers always-hot, S3 compatible object storage at a fraction of the cost of traditional providers like Amazon S3. This cost-effectiveness, combined with CHESA’s expertise in designing and integrating scalable systems, ensures organizations can:

  • Scale their storage needs as projects grow or shrink.
  • Optimize budgets without compromising on performance.
  • Rely on predictable pricing that avoids surprise costs.

Enhanced data security and accessibility

In the media world, accessibility and security are paramount. Backblaze and CHESA provide solutions that keep media assets safe while ensuring real-time access for production teams. Key benefits include:

  • Secure, encrypted storage to protect sensitive media.
  • High availability for instant access to files when needed.
  • Resiliency and redundancy to ensure data integrity, even in the face of unexpected disruptions.

These capabilities have been critical for clients like professional sports teams, broadcasters, and creative agencies that manage vast libraries of high-value media content.

Comprehensive support and maintenance

CHESA’s dedicated support services and Backblaze’s reliable cloud infrastructure ensure organizations experience minimal downtime and sustained operational efficiency. This comprehensive support includes:

  • Proactive monitoring and maintenance.
  • Remote and onsite assistance for hardware, software, and workflows.
  • Consistent communication to address issues before they impact production.

Why this partnership matters

The expanded Backblaze and CHESA partnership is more than just a collaboration—it’s a commitment to empowering media organizations with innovative, efficient, and secure solutions. Here’s why it stands out:

  • Deeply customized solutions: Every organization’s needs are unique. Backblaze Solution Engineers and CHESA Workflow Engineers dive deep into clients’ specific workflows and objectives to design and implement solutions specifically tailored to their needs.
  • Unrivaled expertise, built over decades: Rely on the combined power of Backblaze and CHESA’s deep-rooted experience in cloud storage and media technology.
  • Your future-proof media strategy: Navigate the changing media landscape with confidence, leveraging our scalable and cutting-edge solutions.

Take the next step

Whether you’re a professional sports team looking to enhance fan engagement, a broadcaster aiming to streamline production, or a creative agency seeking cost-effective storage, Backblaze and CHESA are here to help.

Discover how our expanded solutions can revolutionize your media workflows. Visit our dedicated solution page to learn more and to schedule a consultation tailored to your organization’s needs.

Learn More about Backblaze + CHESA  ➔ 

The post Backblaze and CHESA: Doubling Down on a Premier Media Workflow Partnership appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

AWS Pi Day 2025: Data foundation for analytics and AI

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-pi-day-data-foundation-for-analytics-and-ai/

Every year on March 14 (3.14), AWS Pi Day highlights AWS innovations that help you manage and work with your data. What started in 2021 as a way to commemorate the fifteenth launch anniversary of Amazon Simple Storage Service (Amazon S3) has now grown into an event that highlights how cloud technologies are transforming data management, analytics, and AI.

This year, AWS Pi Day returns with a focus on accelerating analytics and AI innovation with a unified data foundation on AWS. The data landscape is undergoing a profound transformation as AI emerges in most enterprise strategies, with analytics and AI workloads increasingly converging around a lot of the same data and workflows. You need an easy way to access all your data and use all your preferred analytics and AI tools in a single integrated experience. This AWS Pi Day, we’re introducing a slate of new capabilities that help you build unified and integrated data experiences.

The next generation of Amazon SageMaker: The center of all your data, analytics, and AI
At re:Invent 2024, we introduced the next generation of Amazon SageMaker, the center of all your data, analytics, and AI. SageMaker includes virtually all the components you need for data exploration, preparation and integration, big data processing, fast SQL analytics, machine learning (ML) model development and training, and generative AI application development. With this new generation of Amazon SageMaker, SageMaker Lakehouse provides you with unified access to your data and SageMaker Catalog helps you to meet your governance and security requirements. You can read the launch blog post written by my colleague Antje to learn more details.

Core to the next generation of Amazon SageMaker is SageMaker Unified Studio, a single data and AI development environment where you can use all your data and tools for analytics and AI. SageMaker Unified Studio is now generally available.

SageMaker Unified Studio facilitates collaboration among data scientists, analysts, engineers, and developers as they work on data, analytics, AI workflows, and applications. It provides familiar tools from AWS analytics and artificial intelligence and machine learning (AI/ML) services, including data processing, SQL analytics, ML model development, and generative AI application development, into a single user experience.

SageMaker Unified Studio

SageMaker Unified Studio also brings selected capabilities from Amazon Bedrock into SageMaker. You can now rapidly prototype, customize, and share generative AI applications using foundation models (FMs) and advanced features such as Amazon Bedrock Knowledge BasesAmazon Bedrock Guardrails, Amazon Bedrock Agents, and Amazon Bedrock Flows to create tailored solutions aligned with your requirements and responsible AI guidelines all within SageMaker.

Last but not least, Amazon Q Developer is now generally available in SageMaker Unified Studio. Amazon Q Developer provides generative AI powered assistance for data and AI development. It helps you with tasks like writing SQL queries, building extract, transform, and load (ETL) jobs, and troubleshooting, and is available in the Free tier and Pro tier for existing subscribers.

You can learn more about SageMaker Unified Studio in this recent blog post written by my colleague Donnie.

During re:Invent 2024, we also launched Amazon SageMaker Lakehouse as part of the next generation of SageMaker. SageMaker Lakehouse unifies all your data across Amazon S3 data lakes, Amazon Redshift data warehouses, and third-party and federated data sources. It helps you build powerful analytics and AI/ML applications on a single copy of your data. SageMaker Lakehouse gives you the flexibility to access and query your data in-place with Apache Iceberg–compatible tools and engines. In addition, zero-ETL integrations automate the process of bringing data into SageMaker Lakehouse from AWS data sources such as Amazon Aurora or Amazon DynamoDB and from applications such as Salesforce, Facebook Ads, Instagram Ads, ServiceNow, SAP, Zendesk, and Zoho CRM. The full list of integrations is available in the SageMaker Lakehouse FAQ.

Building a data foundation with Amazon S3
Building a data foundation is the cornerstone of accelerating analytics and AI workloads, enabling organizations to seamlessly manage, discover, and utilize their data assets at any scale. Amazon S3 is the world’s best place to build a data lake, with virtually unlimited scale, and it provides the essential foundation for this transformation.

I’m always astonished to learn about the scale at which we operate Amazon S3: It currently holds over 400 trillion objects, exabytes of data, and processes a mind-blowing 150 million requests per second. Just a decade ago, not even 100 customers were storing more than a petabyte (PB) of data on S3. Today, thousands of customers have surpassed the 1 PB milestone.

Amazon S3 stores exabytes of tabular data, and it averages over 15 million requests to tabular data per second. To help you reduce the undifferentiated heavy lifting when managing your tabular data in S3 buckets, we announced Amazon S3 Tables at AWS re:Invent 2024. S3 Tables are the first cloud object store with built-in support for Apache Iceberg. S3 tables are specifically optimized for analytics workloads, resulting in up to threefold faster query throughput and up to tenfold higher transactions per second compared to self-managed tables.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse  Amazon S3 Tables now integrate with Amazon SageMaker Lakehouse, making it easy for you to access S3 Tables from AWS analytics services such as Amazon Redshift, Amazon Athena, Amazon EMR, AWS Glue, and Apache Iceberg–compatible engines such as Apache Spark or PyIceberg. SageMaker Lakehouse enables centralized management of fine-grained data access permissions for S3 Tables and other sources and consistently applies them across all engines.

For those of you who use a third-party catalog, have a custom catalog implementation, or only need basic read and write access to tabular data in a single table bucket, we’ve added new APIs that are compatible with the Iceberg REST Catalog standard. This enables any Iceberg-compatible application to seamlessly create, update, list, and delete tables in an S3 table bucket. For unified data management across all of your tabular data, data governance, and fine-grained access controls, you can also use S3 Tables with SageMaker Lakehouse.

To help you access S3 Tables, we’ve launched updates in the AWS Management Console. You can now create a table, populate it with data, and query it directly from the S3 console using Amazon Athena, making it easier to get started and analyze data in S3 table buckets.

The following screenshot shows how to access Athena directly from the S3 console.

S3 console : create table with AthenaWhen I select Query tables with Athena or Create table with Athena, it opens the Athena console on the correct data source, catalog, and database.

S3 Tables in Athena

Since re:Invent 2024, we’ve continued to add new capabilities to S3 Tables at a rapid pace. For example, we added schema definition support to the CreateTable API and you can now create up to 10,000 tables in an S3 table bucket. We also launched S3 Tables into eight additional AWS Regions, with the most recent being Asia Pacific (Seoul, Singapore, Sydney) on March 4, with more to come. You can refer to the S3 Tables AWS Regions page of the documentation to get the list of the eleven Regions where S3 Tables are available today.

Amazon S3 Metadataannounced during re:Invent 2024— has been generally available since January 27. It’s the fastest and easiest way to help you discover and understand your S3 data with automated, effortlessly-queried metadata that updates in near real time. S3 Metadata works with S3 object tags. Tags help you logically group data for a variety of reasons, such as to apply IAM policies to provide fine-grained access, specify tag-based filters to manage object lifecycle rules, and selectively replicate data to another Region. In Regions where S3 Metadata is available, you can capture and query custom metadata that is stored as object tags. To reduce the cost associated with object tags when using S3 Metadata, Amazon S3 reduced pricing for S3 object tagging by 35 percent in all Regions, making it cheaper to use custom metadata.

AWS Pi Day 2025
Over the years, AWS Pi Day has showcased major milestones in cloud storage and data analytics. This year, the AWS Pi Day virtual event will feature a range of topics designed for developers and technical decision-makers, data engineers, AI/ML practitioners, and IT leaders. Key highlights include deep dives, live demos, and expert sessions on all the services and capabilities I discussed in this post.

By attending this event, you’ll learn how you can accelerate your analytics and AI innovation. You’ll learn how you can use S3 Tables with native Apache Iceberg support and S3 Metadata to build scalable data lakes that serve both traditional analytics and emerging AI/ML workloads. You’ll also discover the next generation of Amazon SageMaker, the center for all your data, analytics, and AI, to help your teams collaborate and build faster from a unified studio, using familiar AWS tools with access to all your data whether it’s stored in data lakes, data warehouses, or third-party or federated data sources.

For those looking to stay ahead of the latest cloud trends, AWS Pi Day 2025 is an event you can’t miss. Whether you’re building data lakehouses, training AI models, building generative AI applications, or optimizing analytics workloads, the insights shared will help you maximize the value of your data.

Tune in today and explore the latest in cloud data innovation. Don’t miss the opportunity to engage with AWS experts, partners, and customers shaping the future of data, analytics, and AI.

If you missed the virtual event on March 14, you can visit the event page at any time—we will keep all the content available on-demand there!

— seb


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Collaborate and build faster with Amazon SageMaker Unified Studio, now generally available

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/collaborate-and-build-faster-with-amazon-sagemaker-unified-studio-now-generally-available/

Today, we’re announcing the general availability of Amazon SageMaker Unified Studio, a single data and AI development environment where you can find and access all of the data in your organization and act on it using the best tool for the job across virtually any use case. Introduced as preview during AWS re:Invent 2024, my colleague, Antje, summarized it as:

SageMaker Unified Studio (preview) is a single data and AI development environment. It brings together functionality and tools from the range of standalone “studios,” query editors, and visual tools that we have today in Amazon AthenaAmazon EMRAWS GlueAmazon RedshiftAmazon Managed Workflows for Apache Airflow (Amazon MWAA), and the existing SageMaker Studio.

Here’s a video to see Amazon SageMaker Unified Studio in action:

SageMaker Unified Studio breaks down silos in data and tools, giving data engineers, data scientists, data analysts, ML developers and other data practitioners a single development experience. This saves development time and simplifies access control management so data practitioners can focus on what really matters to them—building data products and AI applications.

This post focuses on several important announcements that we’re excited to share:

To get started, go to the Amazon SageMaker console and create a SageMaker Unified Studio domain. To learn more, visit Create an Amazon SageMaker Unified Studio domain in the AWS documentation.

New capabilities for Amazon Bedrock in SageMaker Unified Studio
The capabilities of Amazon Bedrock within Amazon SageMaker Unified Studio offer a governed collaborative environment for developers to rapidly create and customize generative AI applications. This intuitive interface caters to developers of all skill levels, providing seamless access to the high-performance FMs offered in Amazon Bedrock and advanced customization tools for collaborative development of tailored generative AI applications.

Since the preview launch, several new FMs have become available in Amazon Bedrock and are fully integrated with SageMaker Unified Studio, including Anthropic’s Claude 3.7 Sonnet and DeepSeek-R1. These models can be used for building generative AI apps and chatting in the playground in SageMaker Unified Studio.

Here’s how you can choose Anthropic’s Claude 3.7 Sonnet on the model selection in your project.

You can also source data or documents from S3 folders within your project and select specific FMs when creating knowledge bases. 

During preview, we introduced Amazon Bedrock Guardrails to help you implement safeguards for your Amazon Bedrock application based on your use cases and responsible AI policies. Now, Amazon Bedrock Guardrails is extended to Amazon Bedrock Flows with this general availability release.

Additionally, we have streamlined generative AI setup for associated accounts with a new user management interface in SageMaker Unified Studio, making it straightforward for domain administrators to grant associated account admins access to model governance projects. This enhancement eliminates the need for command line operations, streamlining the process of configuring generative AI capabilities across multiple AWS accounts.

These new features eliminate barriers between data, tools, and builders in the generative AI development process. You and your team will gain a unified development experience by incorporating the powerful generative AI capabilities of Amazon Bedrock — all within the same workspace.

Amazon Q Developer is now generally available in SageMaker Unified Studio
Amazon Q Developer is now generally available in Amazon SageMaker Unified Studio, providing data professionals with generative AI–powered assistance across the entire data and AI development lifecycle.

Amazon Q Developer integrates with the full suite of AWS analytics and AI/ML tools and services within SageMaker Unified Studio, including data processing, SQL analytics, machine learning model development, and generative AI application development, to accelerate collaboration and help teams build data and AI products faster. To get started, you can select Amazon Q Developer icon.

For new users of SageMaker Unified Studio, Amazon Q Developer serves as an invaluable onboarding assistant. It can explain core concepts such as domains and projects, provide guidance on setting up environments, and answer your questions.

Amazon Q Developer helps you discover and understand data using powerful natural language interactions with SageMaker Catalog. What makes this implementation particularly powerful is how Amazon Q Developer combines broad knowledge of AWS analytics and AI/ML services with the user’s context to provide personalized guidance.

You can chat about your data assets through a conversational interface, asking questions such as “Show all payment related datasets” without needing to navigate complex metadata structures.

Amazon Q Developer offers SQL query generation through its integration with the built-in query editor available in SageMaker Unified Studio. Data professionals of varying skill levels can now express their analytical needs in natural language, receiving properly formatted SQL queries in return.

For example, you can ask, “Analyze payment method preferences by age group and region” and Amazon Q Developer will generate the appropriate SQL with proper joins across multiple tables.

Additionally, Amazon Q Developer is also available to assist with troubleshooting and generating real-time code suggestions in SageMaker Unified Studio Jupyter notebooks, as well as building ETL jobs.

Now available

  • Availability — Amazon SageMaker Unified Studio is now available in the following AWS Regions: US East (N. Virginia, Ohio), US West (Oregon), Asia Pacific (Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London), South America (São Paulo). Learn more about the availability of these capabilities on supported Region documentation page.
  • Amazon Q Developer subscription — The free tier of Amazon Q Developer is available by default in SageMaker Unified Studio, requiring no additional setup or configuration. If you already have Amazon Q Developer Pro Tier subscriptions, you can use those enhanced capabilities within the SageMaker Unified Studio environment. For more information, visit the documentation page.
  • Amazon Bedrock capabilities — To learn more about the capabilities of Amazon Bedrock in Amazon SageMaker Unified Studio, refer to this documentation page

Start building with Amazon SageMaker Unified Studio today. For more information, visit the Amazon SageMaker Unified Studio page.

Happy building!

Donnie Prakoso

— How is the News Blog doing? Take this 1 minute survey! (This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Amazon S3 Tables integration with Amazon SageMaker Lakehouse is now generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-s3-tables-integration-with-amazon-sagemaker-lakehouse-is-now-generally-available/

At re:Invent 2024, we launched Amazon S3 Tables, the first cloud object store with built-in Apache Iceberg support to streamline storing tabular data at scale, and Amazon SageMaker Lakehouse to simplify analytics and AI with a unified, open, and secure data lakehouse. We also previewed S3 Tables integration with Amazon Web Services (AWS) analytics services for you to stream, query, and visualize S3 Tables data using Amazon Athena, Amazon Data Firehose, Amazon EMR, AWS Glue, Amazon Redshift, and Amazon QuickSight.

Our customers wanted to simplify the management and optimization of their Apache Iceberg storage, which led to the development of S3 Tables. They were simultaneously working to break down data silos that impede analytics collaboration and insight generation using the SageMaker Lakehouse. When paired with S3 Tables and SageMaker Lakehouse in addition to built-in integration with AWS analytics services, they can gain a comprehensive platform unifying access to multiple data sources enabling both analytics and machine learning (ML) workflows.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse to provide unified S3 Tables data access across various analytics engines and tools. You can access SageMaker Lakehouse from Amazon SageMaker Unified Studio, a single data and AI development environment that brings together functionality and tools from AWS analytics and AI/ML services. All S3 tables data integrated with SageMaker Lakehouse can be queried from SageMaker Unified Studio and engines such as Amazon Athena, Amazon EMR, Amazon Redshift, and Apache Iceberg-compatible engines like Apache Spark or PyIceberg.

With this integration, you can simplify building secure analytic workflows where you can read and write to S3 Tables and join with data in Amazon Redshift data warehouses and third-party and federated data sources, such as Amazon DynamoDB or PostgreSQL.

You can also centrally set up and manage fine-grained access permissions on the data in S3 Tables along with other data in the SageMaker Lakehouse and consistently apply them across all analytics and query engines.

S3 Tables integration with SageMaker Lakehouse in action
To get started, go to the Amazon S3 console and choose Table buckets from the navigation pane and select Enable integration to access table buckets from AWS analytics services.

Now you can create your table bucket to integrate with SageMaker Lakehouse. To learn more, visit Getting started with S3 Tables in the AWS documentation.

1. Create a table with Amazon Athena in the Amazon S3 console
You can create a table, populate it with data, and query it directly from the Amazon S3 console using Amazon Athena with just a few steps. Select a table bucket and select Create table with Athena, or you can select an existing table and select Query table with Athena.

2. Create tables with Athena

When you want to create a table with Athena, you should first specify a namespace for your table. The namespace in an S3 table bucket is equivalent to a database in AWS Glue, and you use the table namespace as the database in your Athena queries.

Choose a namespace and select Create table with Athena. It goes to the Query editor in the Athena console. You can create a table in your S3 table bucket or query data in the table.

2. Query with Athena

2. Query with SageMaker Lakehouse in the SageMaker Unified Studio
Now you can access unified data across S3 data lakes, Redshift data warehouses, third-party and federated data sources in SageMaker Lakehouse directly from SageMaker Unified Studio.

To get started, go to the SageMaker console and create a SageMaker Unified Studio domain and project using a sample project profile: Data Analytics and AI-ML model development. To learn more, visit Create an Amazon SageMaker Unified Studio domain in the AWS documentation.

After the project is created, navigate to the project overview and scroll down to project details to note down the project role Amazon Resource Name (ARN).

3. Project details in SageMaker Unified Studio

Go to the AWS Lake Formation console and grant permissions for AWS Identity and Access Management (IAM) users and roles. In the in the Principals section, select the <project role ARN> noted in the previous paragraph. Choose Named Data Catalog resources in the LF-Tags or catalog resources section and select the table bucket name you created for Catalogs. To learn more, visit Overview of Lake Formation permissions in the AWS documentation.

4. Grant permissions in Lake Formation console

When you return to SageMaker Unified Studio, you can see your table bucket project under Lakehouse in the Data menu in the left navigation pane of project page. When you choose Actions, you can select how to query your table bucket data in Amazon Athena, Amazon Redshift, or JupyterLab Notebook.

5. S3 Tables in Unified Studio

When you choose Query with Athena, it automatically goes to Query Editor to run data query language (DQL) and data manipulation language (DML) queries on S3 tables using Athena.

Here is a sample query using Athena:

select * from "s3tablecatalog/s3tables-integblog-bucket”.”proddb"."customer" limit 10;

6. Athena query in Unified Studio

To query with Amazon Redshift, you should set up Amazon Redshift Serverless compute resources for data query analysis. And then you choose Query with Redshift and run SQL in the Query Editor. If you want to use JupyterLab Notebook, you should create a new JupyterLab space in Amazon EMR Serverless.

3. Join data from other sources with S3 Tables data
With S3 Tables data now available in SageMaker Lakehouse, you can join it with data from data warehouses, online transaction processing (OLTP) sources like relational or non-relational database, Iceberg tables, and other third party sources to gain more comprehensive and deeper insights.

For example, you can add connections to data sources such as Amazon DocumentDB, Amazon DynamoDB, Amazon Redshift, PostgreSQL, MySQL, Google BigQuery, or Snowflake and combine data using SQL without extract, transform, and load (ETL) scripts.

Now you can run the SQL query in the Query editor to join the data in the S3 Tables with the data in the DynamoDB.

Here is a sample query to join between Athena and DynamoDB:

select * from "s3tablescatalog/s3tables-integblog-bucket"."blogdb"."customer", 
              "dynamodb1"."default"."customer_ddb" where cust_id=pid limit 10;

To learn more about this integration, visit Amazon S3 Tables integration with Amazon SageMaker Lakehouse in the AWS documentation.

Now available
S3 Tables integration with SageMaker Lakehouse is now generally available in all AWS Regions where S3 Tables are available. To learn more, visit the S3 Tables product page and the SageMaker Lakehouse page.

Give S3 Tables a try in the SageMaker Unified Studio today and send feedback to AWS re:Post for Amazon S3 and AWS re:Post for Amazon SageMaker or through your usual AWS Support contacts.

In the annual celebration of the launch of Amazon S3, we will introduce more awesome launches for Amazon S3 and Amazon SageMaker. To learn more, join the AWS Pi Day event on March 14.

Channy

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Watch the recordings from AWS Developer Day 2025

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/watch-the-recordings-from-aws-developer-day-2025/

Software development is undergoing a seismic shift, driven by the transformative impact of generative AI. This powerful technology is redefining how developers work, what they build, and who can become a developer. At the AWS Developer Day 2025, we discussed how AWS is empowering developers to embrace this evolution through their generative AI developer tools. Developers got a first-hand look at exciting product launches, updates, and insights from AWS leaders on the future of software development. See the session list below.

Behind the scenes photo of Eva Knight, Artur Rodrigues, Farrah Campbell and AM Grobelny rehursing their session. Camera equipment in the foreground with speakers at a desk in the background.

This free, virtual event inspired developers of all backgrounds about the possibilities of generative AI for their work. Through use case demos, leadership insights, and community spotlights, attendees learned how AWS is making it faster and easier to build and scale quality software in the cloud.

If you could not attend AWS Developer Day 2025, you can still watch the recordings on YouTube:

The AWS Developer Day 2025 showcased the transformative power of generative AI for software development. Developers learned how AWS is empowering them to embrace this evolution through their generative AI developer tools, making it faster and easier to build and scale quality software in the cloud. From boosting productivity across the SDLC to accelerating application modernization, the event highlighted the exciting possibilities that generative AI offers for the future of software development. As the industry continues to evolve, AWS is committed to equipping developers with the tools and insights they need to thrive in this changing landscape.

DeepSeek-R1 now available as a fully managed serverless model in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-r1-now-available-as-a-fully-managed-serverless-model-in-amazon-bedrock/

As of January 30, DeepSeek-R1 models became available in Amazon Bedrock through the Amazon Bedrock Marketplace and Amazon Bedrock Custom Model Import. Since then, thousands of customers have deployed these models in Amazon Bedrock. Customers value the robust guardrails and comprehensive tooling for safe AI deployment. Today, we’re making it even easier to use DeepSeek in Amazon Bedrock through an expanded range of options, including a new serverless solution.

The fully managed DeepSeek-R1 model is now generally available in Amazon Bedrock. Amazon Web Services (AWS) is the first cloud service provider (CSP) to deliver DeepSeek-R1 as a fully managed, generally available model. You can accelerate innovation and deliver tangible business value with DeepSeek on AWS without having to manage infrastructure complexities. You can power your generative AI applications with DeepSeek-R1’s capabilities using a single API in the Amazon Bedrock’s fully managed service and get the benefit of its extensive features and tooling.

According to DeepSeek, their model is publicly available under MIT license and offers strong capabilities in reasoning, coding, and natural language understanding. These capabilities power intelligent decision support, software development, mathematical problem-solving, scientific analysis, data insights, and comprehensive knowledge management systems.

As is the case for all AI solutions, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results. When implementing publicly available models like DeepSeek-R1, consider the following:

  • Data security – You can access the enterprise-grade security, monitoring, and cost control features of Amazon Bedrock that are essential for deploying AI responsibly at scale, all while retaining complete control over your data. Users’ inputs and model outputs aren’t shared with any model providers. You can use these key security features by default, including data encryption at rest and in transit, fine-grained access controls, secure connectivity options, and download various compliance certifications while communicating with the DeepSeek-R1 model in Amazon Bedrock.
  • Responsible AI – You can implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. This includes key features of content filtering, sensitive information filtering, and customizable security controls to prevent hallucinations using contextual grounding and Automated Reasoning checks. This means you can control the interaction between users and the DeepSeek-R1 model in Bedrock with your defined set of policies by filtering undesirable and harmful content in your generative AI applications.
  • Model evaluation – You can evaluate and compare models to identify the optimal model for your use case, including DeepSeek-R1, in a few steps through either automatic or human evaluations by using Amazon Bedrock model evaluation tools. You can choose automatic evaluation with predefined metrics such as accuracy, robustness, and toxicity. Alternatively, you can choose human evaluation workflows for subjective or custom metrics such as relevance, style, and alignment to brand voice. Model evaluation provides built-in curated datasets, or you can bring in your own datasets.

We strongly recommend integrating Amazon Bedrock Guardrails and using Amazon Bedrock model evaluation features with your DeepSeek-R1 model to add robust protection for your generative AI applications. To learn more, visit Protect your DeepSeek model deployments with Amazon Bedrock Guardrails and Evaluate the performance of Amazon Bedrock resources.

Get started with the DeepSeek-R1 model in Amazon Bedrock
If you’re new to using DeepSeek-R1 models, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-R1 model, request access for DeepSeek-R1 in DeepSeek. You’ll then be granted access to the model in Amazon Bedrock.

Next, to test the DeepSeek-R1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-R1 as the model. Then choose Apply.

Using the selected DeepSeek-R1 model, I run the following prompt example:

A family has $5,000 to save for their vacation next year. They can place the money in a savings account earning 2% interest annually or in a certificate of deposit earning 4% interest annually but with no access to the funds until the vacation. If they need $1,000 for emergency expenses during the year, how should they divide their money between the two options to maximize their vacation fund?

This prompt requires a complex chain of thought and produces very precise reasoning results.

To learn more about usage recommendations for prompts, refer to the README of the DeepSeek-R1 model in its GitHub repository.

By choosing View API request, you can also access the model using code examples in the AWS Command Line Interface (AWS CLI) and AWS SDK. You can use us.deepseek.r1-v1:0 as the model ID.

Here is a sample of the AWS CLI command:

aws bedrock-runtime invoke-model \
     --model-id us.deepseek-r1-v1:0 \
     --body "{\"messages\":[{\"role\":\"user\",\"content\":[{\"type\":\"text\",\"text\":\"[n\"}]}],max_tokens\":2000,\"temperature\":0.6,\"top_k\":250,\"top_p\":0.9,\"stop_sequences\":[\"\\n\\nHuman:\"]}" \
     --cli-binary-format raw-in-base64-out \
     --region us-west-2 \
     invoke-model-output.txt

The model supports both the InvokeModel and Converse API. The following Python code examples show how to send a text message to the DeepSeek-R1 model using the Amazon Bedrock Converse API for text generation.

import boto3
from botocore.exceptions import ClientError

# Create a Bedrock Runtime client in the AWS Region you want to use.
client = boto3.client("bedrock-runtime", region_name="us-west-2")

# Set the model ID, e.g., Llama 3 8b Instruct.
model_id = "us.deepseek.r1-v1:0"

# Start a conversation with the user message.
user_message = "Describe the purpose of a 'hello world' program in one line."
conversation = [
    {
        "role": "user",
        "content": [{"text": user_message}],
    }
]

try:
    # Send the message to the model, using a basic inference configuration.
    response = client.converse(
        modelId=model_id,
        messages=conversation,
        inferenceConfig={"maxTokens": 2000, "temperature": 0.6, "topP": 0.9},
    )

    # Extract and print the response text.
    response_text = response["output"]["message"]["content"][0]["text"]
    print(response_text)

except (ClientError, Exception) as e:
    print(f"ERROR: Can't invoke '{model_id}'. Reason: {e}")
    exit(1)

To enable Amazon Bedrock Guardrails on the DeepSeek-R1 model, select Guardrails under Safeguards in the left navigation pane, and create a guardrail by configuring as many filters as you need. For example, if you filter for “politics” word, your guardrails will recognize this word in the prompt and show you the blocked message.

4. Apply the Bedrock Guardrails to the DeepSeek-R1 model

You can test the guardrail with different inputs to assess the guardrail’s performance. You can refine the guardrail by setting denied topics, word filters, sensitive information filters, and blocked messaging until it matches your needs.

To learn more about Amazon Bedrock Guardrails, visit Stop harmful content in models using Amazon Bedrock Guardrails in the AWS documentation or other deep dive blog posts about Amazon Bedrock Guardrails on the AWS Machine Learning Blog channel.

Here’s a demo walkthrough highlighting how you can take advantage of the fully managed DeepSeek-R1 model in Amazon Bedrock:

Now available
DeepSeek-R1 is now available fully managed in Amazon Bedrock in the US East (N. Virginia), US East (Ohio), and US West (Oregon) AWS Regions through cross-Region inference. Check the full Region list for future updates. To learn more, check out the DeepSeek in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give the DeepSeek-R1 model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Channy

Updated on March 10, 2025 — Fixed a screenshot of model selection and model ID.

Scale and deliver game streaming experiences with Amazon GameLift Streams

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/scale-and-deliver-game-streaming-experiences-with-amazon-gamelift-streams/

Since 2016, game developers have been using Amazon GameLift to power games with dedicated, scalable server hosting capable of supporting 100M concurrent users (CCU) in a single game. Responding to customer requests for additional managed compute capabilities beyond game servers, we’re announcing Amazon GameLift Streams — a new capability in Amazon GameLift to help game publishers build and deliver global, direct-to-player game streaming experiences. As part of this announcement, existing capabilities in Amazon GameLift are now known as Amazon Gamelift Servers, continuing to serve hundreds of developers including industry leaders Ubisoft, Zynga, WB Games, and Meta.

Amazon GameLift Streams helps you deliver game streaming experiences at up to 1080p resolution and 60 frames per second across devices including iOS, Android, and PCs. In just a few clicks, you can deploy games built with a variety of 3D engines, without modifications, onto fully-managed cloud-based GPU instances and stream games through the AWS Network Backbone directly to any device with a web browser.

Amazon GameLift Streams helps you distribute your games direct-to-players, without having to invest millions of dollars in infrastructure and software development to build your own service. Players can start gaming in just a few seconds, without waiting for downloads or installs.

Here’s a quick look at Amazon GameLift Streams:

You can use the Amazon GameLift Streams SDK to integrate with your existing identity services, storefronts, game launchers, websites, or newly created experiences such as playable demos, and begin streaming to players. You can monitor active streams and usage from within the AWS console, and seamlessly scale your streaming infrastructure across multiple regions on the AWS global network to reach more players around the world with low-latency gameplay. Amazon GameLift Streams is the only solution that enables you to upload your game content onto fully-managed GPU instances in the cloud and start streaming in minutes, with little or no modification of your code.

Players can access AAA, AA, and indie games on PCs, phones, tablets, smart TVs, or any device with a WebRTC-enabled browser. Amazon GameLift Streams allows you to dynamically scale streaming capacity to match player demand, ensuring you only pay for what you need. You can choose from a selection of GPU instances that offer a range of price performance, and rely on the built-in security of AWS to protect your intellectual property.

Let’s get started
To begin using Amazon GameLift Streams, I need an existing Amazon GameLift Streams implementation. I prepare my game files by following the Amazon GameLift Streams documentation.

Then, I’ll upload my files to Amazon Simple Storage Service (Amazon S3). I can use the AWS Management Console or this AWS Command Line Interface (AWS CLI) command to upload my game files:

aws s3 sync my-game-folder s3://my-bucket/my-game-path

The next step is to create an Amazon GameLift Streams application. I navigate to the Amazon GameLift Streams console. This is how the new AWS GameLift Streams console looks:

On the Amazon GameLift Streams console, I choose Create application.

In the Runtime settings, I select the runtime environment for my game application.

Then, I need to select my S3 bucket and folder from the previous step, then set the path to my game’s main executable.

I also have the option to configure the automatic transfer of application-generated log files into a S3 bucket. After I’m done with this configuration, I choose Create application.

After my application setup is completed, I need to create a stream group, a collection of compute resources to run and stream the application. I navigate to Stream groups in the left navigation pane of the Amazon GameLift Streams console.

On this page, I define a description for my new stream group.

Here, I select the capabilities and pricing of my stream group. Since my application is using Microsoft Windows Server 2022 Base, I make sure to select one of the compatible stream classes.

Next, I need to link with the application I created in the previous step.

On the Configure stream settings page, I can configure additional locations for my stream group, bringing in additional capacity from other AWS Regions. There are two capacity options that I can choose, always-on capacity and on-demand capacity. The default capacity setting provides one streaming slot, which is sufficient for initial testing.

Then, I need to review my configuration and choose Create stream group.

With stream groups configured, I can test my game streaming. I navigate to the Test stream page on the console to launch my application as a stream. I select this stream group and select Choose.

On the next page, I can configure any command line arguments or environment variables to run my application. I don’t need any extra configurations and choose Test stream.

Then, I can see that my application is running as expected. I can also interact with my game. This test helps me verify that my game works properly in streaming mode and serves as an initial proof of concept.

After I’ve confirmed everything works, I can integrate the Web SDK into my own website. The Web SDK and AWS Software Development Kit (AWS SDK) with Amazon GameLift Streams APIs help me to embed game streams, similar to what I tested in the console, into any web page I manage.

Additional things to know

  • Availability – Amazon GameLift Streams is currently available in the following AWS Regions: US East (Ohio), US West (Oregon), Asia Pacific (Tokyo), Europe (Frankfurt). Additional streaming capacity can also be configured in US East (N. Virginia) and Europe (Ireland).
  • Supported operating systems – Amazon GameLift Streams supports games running on Windows, Linux, or Proton, offering easy onboarding and compatibility with game binaries. Learn more on Choosing a configuration in Amazon GameLift Streams documentation page.
  • Programmatic access – This new capability provides comprehensive tools including service APIs, client streaming SDKs, and AWS CLI for content packaging.

Now available
Explore how to streamline your game distribution using Amazon GameLift Streams. Learn more about getting started on the Amazon GameLift Streams page.

Happy streaming!

Donnie

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Network Stats: Launching the CA-East Region in Canada

Post Syndicated from Brent Nowak original https://www.backblaze.com/blog/network-stats-launching-the-ca-east-region-in-canada/

A decorative image showing the globe with cloud icons over the Backblaze data center locations.

Over the past few years, Backblaze has expanded our regional footprint, adding capacity in the US-West region, growing in our EU-Central locale, opening a new US-East presence, and, most recently, moving into Canada with CA-East with an initial storage capacity of just under 60PB. 

We approached our most recent expansion into Canada a bit differently, and today, I want to cover some of the new processes and efficiencies that we adopted for this project and how we’re well positioned to serve the Canadian market based on our network connections.

A photograph showing a sculpture of the the Toronto airport code, YYZ.
Backblaze deployment team lands in Toronto.

Scaling infrastructure and calling in the reinforcements

The CA-East data region deployment was our fastest to date, cutting the deployment life cycle (“the ink is signed” to a live production system) down in time by 50%. In this deployment cycle we worked with a third party integrator to help us streamline the process and also leveled up our automation procedures for installing operating systems and our storage software stack. 

Historically we’ve drop-shipped all our equipment such as the networking gear, servers, hard drives, cables, and tools to the destination site for our deployment team to inventory, unbox, and physically install. It’s fun. It’s controlled chaos (if you like that sort of thing)—but for this build cycle we wanted to iterate our process further to ease and enable future growth in a more predictable and scalable fashion by working with a third party to assist with the initial physical build of the racked equipment.

On our end, there’s up-front engineering time documenting how all the fiber, copper, and power cables are organized. We have a cable map for every device, every cable, and every location as well as how it should be connected. It’s heavy on the paperwork side, but it’s time well spent. It allows us to template and stamp out future cabinets with ease. When we need more storage-focused cabinets to deploy additional storage, that’s a cabinet standard. If we need more compute, that’s also a cabinet that can be easily built out from a template. 

The workload on the third party integrator side consists of taking our directions and performing all the physical racking and wiring. Handling all of these tasks takes time. You wouldn’t believe the amount of cardboard and packaging material that you need to process! Unboxing over a hundred servers, thousands of hard drives, and hundreds of fiber and copper cables is no small feat. (Apologies in hindsight for not giving you a marathon unboxing video.) They received all our packaging, then racked and cabled up everything according to our specifications. After inspection and quality control, everything was securely sealed in crates and shipped off to Canada.

A photograph showing several Backblaze servers.
Initial setup and bootstrapping of CA-East cluster at the integrator site.
A photo of Backblaze storage cabinets.
Almost ready for QA and final inspection before shipping to the data center.

Automate all the things

Perform a process once? Sure. Have to do it more than twice? Automate it!

Before shipment out to the data center location, we sent a small team to the integrator site to perform a physical quality assessment of the build and set up remote access, which allowed us to bootstrap the platform as we had access to power and an internet connection. 

Internally, we have a system that has a record of machine serial numbers and their roles (e.g., storage, api, database, etc). When a new machine boots up for the first time on our network, it gets a vanilla operating system installed via our PXE services. This is all parallelized, meaning that we were able to have systems to log in to within a few hours for the entire server set. 

It’s a lot of fun toggling the power buttons one-by-one on over 90 servers, the PXE server network link running hot, and having an entire fleet of servers automatically install an operating system and be ready for further administration within minutes. Quite different from my days of performing floppy disk installs of Windows 95!

With a final inspection and software pass, everything was approved for shipment. The integrators securely boxed up our cabinets and they were on their way to Canada.

CA-East setup

Arriving at the destination site, everything was brought to the data center floor, bolted down, grounded, and energized. Within four hours we had network connectivity with our internet carriers and had set up our secure connections back to our production network to start our Backblaze software installation with our various internal teams. Within a few days, we had around 90 servers running and ready for our Quality Assurance team to start running tests to simulate client activity.

We partnered with Cologix, a leading network-neutral interconnection and hyperscale edge data center provider in North America, as our Canadian data center facility operator for this deployment. Cologix’s digital edge data center is a 20,000-square-foot, Tier III facility with two megawatts of power. It is a highly secure and efficient colocation and interconnection hub that features industry leading cooling designs, robust 24/7 security with biometric dual authentication access, and compliance with SOC 1, SOC 2, HIPAA and PCI-DSS as well as ISO 27001 certification by Schellman.

A photo of Backblaze Storage Pods.
Storage Pods with a few compute servers at the top of each cabinet.
A photo of Backblaze Storage Pods.
CA-East: Network and compute cabinets with room to grow.

Connectivity

Our standard connectivity posture is to connect to three global carriers for the most expansive reach to every network possible, and also to join a local internet exchange (IX) for exchanging traffic between other IX members locally within the same data center or metro region for low-latency efficiency. Additionally, for this site, we also are connected to a large Canadian regional carrier to bring us in close proximity to Canadian-sourced traffic.

With low-latency and diverse dark fiber connectivity between Cologix’s data centers, including Canada’s largest and most important carrier hotel, the facility offers access to 160+ networks, TORIX, and 50+ cloud providers. 

Overall that makes our CA-East connectivity map look like this.

A diagram showing how Backblaze's network traffic is routed through global carriers, regional carriers, and the local level.
Option 1: Global Carriers. Option 2: Regional ISP. Option 3: IX Traffic.

Joining TorIX

The local internet exchange for this site is Toronto Internet Exchange (TorIX),  the leading Canadian internet exchange point (IXP) and one of the largest in the world. At the time of this post, more than 250 organizations exchange on average over 1.3 Terabits per second (Tbit/s) of traffic every day between each other locally.

Connecting to TorIX allows low latency transit between us and internet service providers (ISPs), other clouds, partner content delivery networks (CDNs), other enterprise networks, and hosting providers that provide compute services.

Go live

I’ve been at Backblaze for four years now and have been able to participate on builds to expand our US-West, US-East, and now CA-East regions. Turning on the metaphoric “switch” to make the site live is a little anticlimactic—from a network point of view, the only traffic we see at the start of a new region is our monitoring, internal jobs, and some soft-launched testing or proof of concept (PoC) accounts.

Here’s a sample of the network traffic from when we brought up peering with our carriers and soft launched the data region for our internal QA teams.

A chart showing Backblaze network ingress traffic after the data center was live.
Initial traffic into CA-East at time of launch.

Where is the initial network traffic coming from? With our network telemetry monitoring, we’re able to see the flows in traffic in and out of our network. That network traffic information is enriched with data that adds context to allow us to see how much traffic is coming to or from a particular upstream provider or geographical region.

Here’s a Sankey diagram that shows a snapshot of current traffic from Canadian provinces over different service providers to the Backblaze network, where the larger lines mean more traffic is seen from that particular province or network. Expectedly, Ontario and British Columbia are the two largest sources of traffic. 

A diagram showing network traffic by province and carrier network.
Ingress traffic by province and carrier networks to Backblaze network (BGP AS40401).

Canada is open for business

As the months progress, and as more customers create their accounts in this new data region and point their workloads at this location, we’ll see more traffic. We’ll be excited to see what fun insights we can glean, which we’ll keep you updated on in our Network Stats series. 

As Backblaze continues to grow its network, we’re excited to continue to iterate on our buildouts to make them more efficient. Ultimately, it lets us be more responsive to customer needs quickly. Same great network—just more locations.  

We’re excited to have a footprint in Canada and welcome your storage needs! If you’re interested in learning more about storing your data in Canada, you can read the go-live announcement here.

Ready to store data in CA East?

The new data region is available to customers now, and you can create an account there by selecting “CA East” in the region drop-down when creating a Backblaze account. Already storing data with Backblaze and want to keep a Canadian copy? Leverage our Cloud Replication feature and diversify your storage.

The post Network Stats: Launching the CA-East Region in Canada appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Experimenting with DeepSeek, Backblaze B2, and Drive Stats

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/experimenting-with-deepseek-backblaze-b2-and-drive-stats/

A decorative image showing buildings of many sizes.

As we explained in our recent blog post, AI Reasoning Models: OpenAI o3-mini, o1-mini, and DeepSeek R1, Chinese startup DeepSeek caused a stir when it released its R1 reasoning model in January of this year. Interestingly, DeepSeek R1 has an OpenAI-compatible API, so applications written for OpenAI should work with DeepSeek R1 with just a configuration change. Since I had a suitable sample app all ready to go, I decided to put their claim to the test.

Why, and why not, use DeepSeek?

A major difference between DeepSeek and OpenAI is cost. At the time of writing, DeepSeek charges $0.55 per million input tokens and $2.19 per million output tokens for its R1 model. That’s about 3.6% of OpenAI’s $15.00 per million input tokens and $60.00 per million output tokens for its flagship o1 reasoning model, and about half of o3-mini’s $1.10 per million input tokens and $4.40 per million output tokens.

Set against this is the fact that, in using the DeepSeek platform’s API, you are sending your data to a startup located in China that has been accused by OpenAI of “inappropriately” basing its work on the output of OpenAI’s models. It’s up to you, and your organizations’ data governance policy, whether the trade-off is worthwhile.

Another consideration is the ability to run DeepSeek’s models locally, on your own infrastructure, or, more likely, your chosen provider’s infrastructure, rather than sending requests to the DeepSeek platform. Spinning up my own DeepSeek instance was out of scope for this blog post, but I’ll likely return to it in a future blog post.

Swapping OpenAI for DeepSeek

Last month, I explained how you can build an AI agent with Backblaze B2, LangChain, and Drive Stats, walking you through a simple chatbot that can answer questions based on our Drive Stats data set—11 years of metrics gathered from the Backblaze B2 Cloud Storage platform’s fleet of hard drives. In that example, the chatbot accepted a natural language question, used OpenAI’s GPT‑4o mini large language model (LLM) to generate a SQL query that might help provide an answer, executed the query against the Drive Stats data set via the Trino SQL engine, and then used OpenAI again to interpret the result set and either repeat the query-interpret cycle, or generate a natural language answer.

I copied the Jupyter notebook from that example and used it as the basis for investigating the feasibility of swapping out OpenAI for DeepSeek. The DeepSeek version of the notebook contains the full source code of my experiments; I’ll include relevant extracts here, edited for clarity.

Since I used the LangChain AI framework, which provides a layer above a range of AI models, the only place that OpenAI surfaced in my code was in creating an instance of LangChain’s ChatOpenAI wrapper:

# OPENAI_API_KEY must be defined in the .env file
load_dotenv()
llm = ChatOpenAI(model="gpt-4o-mini")

The ChatOpenAI class contains all the code required to communicate with OpenAI via its API.

According to the DeepSeek documentation, all you should need to do is:

  • Provide your DeepSeek API key in the same OPENAI_API_KEY environment variable.
  • Set the API base URL to https://api.deepseek.com.
  • Provide a DeepSeek model name in place of the OpenAI one.

If this reminds you of the steps for using Backblaze B2’s S3-compatible API, you’re not alone. The OpenAI API has become a de facto standard for integrating with LLMs in much the same way as Amazon’s S3 API allows an ecosystem of apps and tools to interoperate with object storage systems from a variety of vendors.

Looking at the DeepSeek documentation, you can use one of two models, deepseek-reasoner (aka DeepSeek R1) or deepseek-chat. Let’s see what the much-talked-about DeepSeek R1 came up with.

Using DeepSeek R1 in the AI agent

To make it easy to use both the OpenAI and DeepSeek notebooks, I created a second entry in the .env file for the DeepSeek API key, and copied it to the OpenAI environment variable in the notebook code:

# The .env file needs at least DEEPSEEK_API_KEY, and may also contain
# OPENAI_API_KEY. Move the DeepSeek API key to the OpenAI environment
# variable
load_dotenv()

os.environ["OPENAI_API_KEY"] = os.environ.pop("DEEPSEEK_API_KEY")

llm = ChatOpenAI(model="deepseek-reasoner", base_url='https://api.deepseek.com')

As I set about repeating the steps from the Jupyter notebook that supported my previous blog post, I was disappointed to see DeepSeek fall at the very first hurdle: generating a SQL query for a simple natural language question. Here is the code:

question = {"question": "How many drives are there?"}

write_query(question)

Looking back at the original notebook, OpenAI’s response was valid SQL, although it didn’t have enough information to construct the correct query:

{'query': 'SELECT COUNT(*) AS drive_count FROM drivestats'}

DeepSeek, on the other hand, responded with a Python stack trace and this error:

openai.UnprocessableEntityError: Failed to deserialize the JSON body into the target type: response_format: response_format.type `json_schema` is unavailable now at line 1 column 13827

What went wrong? Searching for the error turns up a comment from a LangChain engineer explaining that we should use BaseChatOpenAI rather than ChatOpenAI since it “[…] accommodates many APIs that are similar to OpenAI. It uses tool calling for structured output by default.”

So, we can redefine llm accordingly, and try generating a query again:

llm = BaseChatOpenAI(model="deepseek-reasoner", base_url='https://api.deepseek.com')

write_query(question)

Unfortunately, DeepSeek returns another error:

BadRequestError: Error code: 400 - {'error': {'message': 'The last message of deepseek-reasoner must be a user message, or an assistant message with prefix mode on (refer to https://api-docs.deepseek.com/guides/chat_prefix_completion).', 'type': 'invalid_request_error', 'param': None, 'code': 'invalid_request_error'}}

Looking back at the AI agent code, we can see that we used an off-the-shelf prompt from the LangChain Prompt Hub that provides the model with a single, system, message:

================================ System Message ================================

Given an input question, create a syntactically correct {dialect} query to run to help find the answer. Unless the user specifies in his question a specific number of examples they wish to obtain, always limit your query to at most {top_k} results. You can order the results by a relevant column to return the most interesting examples in the database.

Never query for all the columns from a specific table, only ask for a few relevant columns given the question.

Pay attention to use only the column names that you can see in the schema description. Be careful to not query for columns that do not exist. Also, pay attention to which column is in which table.

Only use the following tables:
{table_info}

Question: {input}

Does this mean that DeepSeek is not, in fact, API-compatible with OpenAI? I would argue that it does not. DeepSeek implements the same API request/response syntax as OpenAI, but it is a different platform. Some variation in semantics is to be expected. We see similar variations between Backblaze B2 and Amazon S3; for example, the S3 PutObjectAcl operation sets the access control list (ACL) for an object in a bucket. Amazon S3’s access management model allows you to manipulate an object’s ACL independently of its bucket—for example, you can put a private object in a public bucket, and vice versa.

This flexibility comes with a cost: It becomes difficult to reason about the visibility of data. In fact, AWS now recommends “that you keep ACLs disabled, except in unusual circumstances where you need to control access for each object individually.”

Backblaze B2’s model is much simpler: You control access at the bucket level, and all objects have the same ACL as their bucket. Backblaze B2 implements the PutObjectAcl operation, but, if you try to set an object’s ACL to any other value than its bucket’s ACL, the service responds with an error.

Returning to the AI agent code, we can replace the single-system-message prompt with one that combines a system message with a user message:

import textwrap
from langchain_core.prompts import ChatPromptTemplate

query_prompt_template = ChatPromptTemplate([
("system", textwrap.dedent("""Given an input question, create a
syntactically correct {dialect} query to run to help find the answer.
Unless the user specifies in his question a specific number of examples
they wish to obtain, always limit your query to at most {top_k} results.
You can order the results by a relevant column to return the most
interesting examples in the database.

Never query for all the columns from a specific table, only ask for a the
few relevant columns given the question.

Pay attention to use only the column names that you can see in the schema
description. Be careful to not query for columns that do not exist. Also,
pay attention to which column is in which table.

Only use the following tables:
{table_info}""")),
("human", "Question: {input}"),
])

Trying the write_query() call for a third time, this is the response:

BadRequestError: Error code: 400 - {'error': {'message': 'deepseek-reasoner does not support Function Calling', 'type': 'invalid_request_error', 'param': None, 'code': 'invalid_request_error'}}

A third error! What is this “function calling” that deepseek-reasoner does not support? A helpful article on the topic at the Hugging Face AI community explains:

Function calling is a powerful capability that enables Large Language Models (LLMs) to interact with your code and external systems in a structured way. Instead of just generating text responses, LLMs can understand when to call specific functions and provide the necessary parameters to execute real-world actions.

Unfortunately, that is exactly our use case. It’s becoming clear that DeepSeek R1 is not the correct tool for implementing an AI agent—we’ve been trying to use a chisel as a screwdriver!

DeepSeek-V3: A better fit

As its name suggests, the deepseek-chat model is more appropriate for this application. The DeepSeek documentation tells us that it is based on DeepSeek-V3, released in December 2024. DeepSeek-V3 is priced at $0.27 per million input tokens and $1.10 per million output tokens; this is actually more expensive than the GPT-4o mini model I used for the OpenAI agent example ($0.15 per million input tokens, $0.600 per million output tokens), but how does it compare? Let’s take a look.

First, we need to edit the LLM creation code again to set the model name:

llm = BaseChatOpenAI(model="deepseek-chat", base_url='https://api.deepseek.com')

Now we can run write_query() again. It’s immediately clear that it’s a better fit than its “big brother:”

{'query': 'SELECT COUNT(*) AS total_drives FROM drivestats LIMIT 10'}

As with the OpenAI agent, this query is well-formed SQL, but it’s not answering the question we set—it’s giving us the total number of rows in the dataset, rather than the number of drives. Also, it’s a little odd to have a LIMIT clause in a SELECT COUNT(*) query, but it’s legal SQL, and the agent is following its instructions very literally: always limit your query to at most {top_k} results, where we set top_k to 10.

question = {"question": "Each drive has its own serial number. How many drives are there?"}

query = write_query(question)

{'query': 'SELECT COUNT(DISTINCT serial_number) AS total_drives FROM drivestats'}

So far, so good!

I’ll skip some intermediate steps here—they are all in the Jupyter notebook if you want to review them, or run them for yourself—and look at how a simple LangChain graph, built on the DeepSeek LLM, answered the question: “Each drive has its own serial number. How many drives did each data center have on 9/1/2024?”

The OpenAI version generated an invalid query, comparing the date column with the string ’2024-09-01’ without using the required DATE type identifier, but DeepSeek generates a correct SQL query and provides a useful natural language response:

/SELECT datacenter, COUNT(DISTINCT serial_number) AS drive_count FROM drivestats WHERE date = DATE ‘2024-09-01’ GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10


[(‘phx1’, 89477), (‘sac0’, 78444), (‘sac2’, 60775), (”, 24080), (‘iad1’, 22800), (‘ams5’, 16139)]


On September 1, 2024, the data centers had the following number of drives:

  • phx1: 89,477 drives
  • sac0: 78,444 drives
  • sac2: 60,775 drives
  • (empty datacenter): 24,080 drives
  • iad1: 22,800 drives
  • ams5: 16,139 drives

These are the top data centers with the highest drive counts on that date.

DeepSeek scores a point!

Moving on to the ReAct AI Agent, which allows the LLM to perform multiple SQL queries in generating an answer to a question, DeepSeek performs similarly to OpenAI. Given the question, “Each drive has its own serial number. What is the annualized failure rate of the ST4000DM000 drive model?”, the DeepSeek agent provides the overall failure rate rather than the annualized failure rate (AFR).

When we provide explicit instructions for calculating AFR in its prompt, the DeepSeek agent provides the correct result, identical, in fact, to the OpenAI agent’s response:

The annual failure rate (AFR) for the ST4000DM000 drive model is approximately 2.63%.

However, when given the question, “What was the annual failure rate of the ST8000NM000A drive model in Q3 2024?”, the DeepSeek agent gives us:

[(1.6100573445081607,)]

While OpenAI responds:

The annual failure rate (AFR) of the ST8000NM000A drive model in Q3 2024 is approximately 1.61%.

Wrapping up the investigation, the final question from the OpenAI notebook is more complex:

Considering only drive models which had at least 100 drives in service at the end of the quarter and which accumulated 10,000 or more drive days during the quarter, which drive had the most failures in Q3 2024, and what was its failure rate?

Impressively, the OpenAI agent constructed a well-formed SQL query and provided the correct response:

The drive model with the most failures in Q3 2024 is the TOSHIBA MG08ACA16TA, which had 181 failures. Its failure rate during this period was approximately 1.84%.

BadRequestError: Error code: 400 - {'error': {'message': "An assistant message with 'tool_calls' must be followed by tool messages responding to each 'tool_call_id'. (insufficient tool messages following tool_calls message)", 'type': 'invalid_request_error', 'param': None, 'code': 'invalid_request_error'}}
During task with name 'agent' and id '0aa26ba6-a3ee-ced1-de4d-b60ed7fbca99'

The phrase “insufficient tool messages” suggested that the DeepSeek LLM might need to be reconfigured to allow more tokens. According to the documentation on models and pricing, the deepseek-chat model supports a maximum of 8K output tokens, but defaults to 4K if max_tokens is not specified.

Recreating the DeepSeek wrapper object and agent accordingly, I gave it the last question again:

llm = BaseChatOpenAI(model="deepseek-chat", base_url='https://api.deepseek.com', max_tokens=8192, **extra_kwargs)

agent_executor = create_react_agent(llm, tools, state_modifier=system_message)

response = agent_executor.invoke(
{"messages": [{"role": "user", "content": "Considering only drive models which had at least 100 drives in service at the end of the quarter and which accumulated 10,000 or more drive days during the quarter, which drive had the most failures in Q3 2024, and what was its failure rate?"}]}
)

# Show the SQL query sent to the database
print(response['messages'][-3].tool_calls[0]['args']['query'])

# Show the final response message
display_markdown(response['messages'][-1].content, raw=True)

This time, DeepSeek was able to generate a similar SQL query to OpenAI:

WITH drive_counts AS (
SELECT model, COUNT(DISTINCT serial_number) AS drive_count
FROM drivestats
WHERE date >= DATE '2024-07-01' AND date <= DATE '2024-09-30'
GROUP BY model
HAVING COUNT(DISTINCT serial_number) >= 100
), drive_days AS (
SELECT model, COUNT(*) AS total_drive_days
FROM drivestats
WHERE date >= DATE '2024-07-01' AND date <= DATE '2024-09-30'
GROUP BY model
HAVING COUNT(*) >= 10000
), failures AS (
SELECT model, COUNT(*) AS failure_count
FROM drivestats
WHERE date >= DATE '2024-07-01' AND date <= DATE '2024-09-30' AND failure = 1
GROUP BY model
)
SELECT d.model,
f.failure_count,
100 * (CAST(f.failure_count AS DOUBLE) / (CAST(d.total_drive_days AS DOUBLE) / 365)) AS annual_failure_rate
FROM drive_days d
JOIN failures f ON d.model = f.model
JOIN drive_counts dc ON d.model = dc.model
ORDER BY f.failure_count DESC
LIMIT 1

With a correct response:

To answer the question:

The drive model with the most failures in Q3 2024 is TOSHIBA MG08ACA16TA, which had 181 failures. The annualized failure rate (AFR) for this model during that quarter was 1.84%.

Success! But, unfortunately, this isn’t the whole story.

DeepSeek Reliability

A screenshot of a DeepSeek error message.

I originally set out to write this blog post at the end of January, but the DeepSeek platform website had gone offline by January 30, so I couldn’t even start until I was able to sign up for an API key on February 5.

A screenshot of DeepSeek availability from December 2024 to Feburary 2025.

Given my shiny new API key, and DeepSeek’s claims of OpenAI API compatibility, I naïvely expected to be able to work through my earlier OpenAI notebook and write up the results in a couple of days. The reality was more like two weeks.

In this blog post I’ve detailed some of the error messages I encountered along the way, but I saw many more that pointed to the DeepSeek API simply being overwhelmed with traffic. For example, for over a day, when the status page reported no issues, most API requests to DeepSeek terminated after a minute with the error message:

json.decoder.JSONDecodeError: Expecting value: line 1 column 1 (char 0)

A time-consuming investigation revealed that this was caused by the DeepSeek API returning the 200 status code and headers as if the request was successful, then hanging for a minute before terminating the connection without returning any actual data. The calling code saw the 200 as success and tried to decode the non-existent API response body, resulting in the error.

I saw several more instances of intermittent errors that all seemed to point in the same direction: DeepSeek needs to add capacity to its API platform. Notably, the platform seemed faster and more stable on a Saturday morning, U.S. Pacific time, the early hours of Sunday morning in China.

Final thoughts

At present, I would have to classify the DeepSeek-V3 API as “promising, but somewhat flaky.” An agent invocation that succeeds one minute could fail the next with any of a range of error messages. That’s a shame, since when it does work, for instance, in creating the SQL query for the final question above, it tends to work very well.

One final caveat: This is a dynamic field; frameworks and services are literally being updated on a daily basis. For example, since yesterday, as I write this, four of the notebook’s module dependencies have been updated. I encourage you to experiment for yourself as your mileage will almost certainly vary, hopefully in a positive direction.

The post Experimenting with DeepSeek, Backblaze B2, and Drive Stats appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Get insights from multimodal content with Amazon Bedrock Data Automation, now generally available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/get-insights-from-multimodal-content-with-amazon-bedrock-data-automation-now-generally-available/

Many applications need to interact with content available through different modalities. Some of these applications process complex documents, such as insurance claims and medical bills. Mobile apps need to analyze user-generated media. Organizations need to build a semantic index on top of their digital assets that include documents, images, audio, and video files. However, getting insights from unstructured multimodal content is not easy to set up: you have to implement processing pipelines for the different data formats and go through multiple steps to get the information you need. That usually means having multiple models in production for which you have to handle cost optimizations (through fine-tuning and prompt engineering), safeguards (for example, against hallucinations), integrations with the target applications (including data formats), and model updates.

To make this process easier, we introduced in preview during AWS re:Invent Amazon Bedrock Data Automation, a capability of Amazon Bedrock that streamlines the generation of valuable insights from unstructured, multimodal content such as documents, images, audio, and videos. With Bedrock Data Automation, you can reduce the development time and effort to build intelligent document processing, media analysis, and other multimodal data-centric automation solutions.

You can use Bedrock Data Automation as a standalone feature or as a parser for Amazon Bedrock Knowledge Bases to index insights from multimodal content and provide more relevant responses for Retrieval-Augmented Generation (RAG).

Today, Bedrock Data Automation is now generally available with support for cross-region inference endpoints to be available in more AWS Regions and seamlessly use compute across different locations. Based on your feedback during the preview, we also improved accuracy and added support for logo recognition for images and videos.

Let’s have a look at how this works in practice.

Using Amazon Bedrock Data Automation with cross-region inference endpoints
The blog post published for the Bedrock Data Automation preview shows how to use the visual demo in the Amazon Bedrock console to extract information from documents and videos. I recommend you go through the console demo experience to understand how this capability works and what you can do to customize it. For this post, I focus more on how Bedrock Data Automation works in your applications, starting with a few steps in the console and following with code samples.

The Data Automation section of the Amazon Bedrock console now asks for confirmation to enable cross-region support the first time you access it. For example:

Console screenshot.

From an API perspective, the InvokeDataAutomationAsync operation now requires an additional parameter (dataAutomationProfileArn) to specify the data automation profile to use. The value for this parameter depends on the Region and your AWS account ID:

arn:aws:bedrock:<REGION>:<ACCOUNT_ID>:data-automation-profile/us.data-automation-v1

Also, the dataAutomationArn parameter has been renamed to dataAutomationProjectArn to better reflect that it contains the project Amazon Resource Name (ARN). When invoking Bedrock Data Automation, you now need to specify a project or a blueprint to use. If you pass in blueprints, you will get custom output. To continue to get standard default output, configure the parameter DataAutomationProjectArn to use arn:aws:bedrock:<REGION>:aws:data-automation-project/public-default.

As the name suggests, the InvokeDataAutomationAsync operation is asynchronous. You pass the input and output configuration and, when the result is ready, it’s written on an Amazon Simple Storage Service (Amazon S3) bucket as specified in the output configuration. You can receive an Amazon EventBridge notification from Bedrock Data Automation using the notificationConfiguration parameter.

With Bedrock Data Automation, you can configure outputs in two ways:

  • Standard output delivers predefined insights relevant to a data type, such as document semantics, video chapter summaries, and audio transcripts. With standard outputs, you can set up your desired insights in just a few steps.
  • Custom output lets you specify extraction needs using blueprints for more tailored insights.

To see the new capabilities in action, I create a project and customize the standard output settings. For documents, I choose plain text instead of markdown. Note that you can automate these configuration steps using the Bedrock Data Automation API.

Console screenshot.

For videos, I want a full audio transcript and a summary of the entire video. I also ask for a summary of each chapter.

Console screenshot.

To configure a blueprint, I choose Custom output setup in the Data automation section of the Amazon Bedrock console navigation pane. There, I search for the US-Driver-License sample blueprint. You can browse other sample blueprints for more examples and ideas.

Sample blueprints can’t be edited, so I use the Actions menu to duplicate the blueprint and add it to my project. There, I can fine-tune the data to be extracted by modifying the blueprint and adding custom fields that can use generative AI to extract or compute data in the format I need.

Console screenshot.

I upload the image of a US driver’s license on an S3 bucket. Then, I use this sample Python script that uses Bedrock Data Automation through the AWS SDK for Python (Boto3) to extract text information from the image:

import json
import sys
import time

import boto3

DEBUG = False

AWS_REGION = '<REGION>'
BUCKET_NAME = '<BUCKET>'
INPUT_PATH = 'BDA/Input'
OUTPUT_PATH = 'BDA/Output'

PROJECT_ID = '<PROJECT_ID>'
BLUEPRINT_NAME = 'US-Driver-License-demo'

# Fields to display
BLUEPRINT_FIELDS = [
    'NAME_DETAILS/FIRST_NAME',
    'NAME_DETAILS/MIDDLE_NAME',
    'NAME_DETAILS/LAST_NAME',
    'DATE_OF_BIRTH',
    'DATE_OF_ISSUE',
    'EXPIRATION_DATE'
]

# AWS SDK for Python (Boto3) clients
bda = boto3.client('bedrock-data-automation-runtime', region_name=AWS_REGION)
s3 = boto3.client('s3', region_name=AWS_REGION)
sts = boto3.client('sts')


def log(data):
    if DEBUG:
        if type(data) is dict:
            text = json.dumps(data, indent=4)
        else:
            text = str(data)
        print(text)

def get_aws_account_id() -> str:
    return sts.get_caller_identity().get('Account')


def get_json_object_from_s3_uri(s3_uri) -> dict:
    s3_uri_split = s3_uri.split('/')
    bucket = s3_uri_split[2]
    key = '/'.join(s3_uri_split[3:])
    object_content = s3.get_object(Bucket=bucket, Key=key)['Body'].read()
    return json.loads(object_content)


def invoke_data_automation(input_s3_uri, output_s3_uri, data_automation_arn, aws_account_id) -> dict:
    params = {
        'inputConfiguration': {
            's3Uri': input_s3_uri
        },
        'outputConfiguration': {
            's3Uri': output_s3_uri
        },
        'dataAutomationConfiguration': {
            'dataAutomationProjectArn': data_automation_arn
        },
        'dataAutomationProfileArn': f"arn:aws:bedrock:{AWS_REGION}:{aws_account_id}:data-automation-profile/us.data-automation-v1"
    }

    response = bda.invoke_data_automation_async(**params)
    log(response)

    return response

def wait_for_data_automation_to_complete(invocation_arn, loop_time_in_seconds=1) -> dict:
    while True:
        response = bda.get_data_automation_status(
            invocationArn=invocation_arn
        )
        status = response['status']
        if status not in ['Created', 'InProgress']:
            print(f" {status}")
            return response
        print(".", end='', flush=True)
        time.sleep(loop_time_in_seconds)


def print_document_results(standard_output_result):
    print(f"Number of pages: {standard_output_result['metadata']['number_of_pages']}")
    for page in standard_output_result['pages']:
        print(f"- Page {page['page_index']}")
        if 'text' in page['representation']:
            print(f"{page['representation']['text']}")
        if 'markdown' in page['representation']:
            print(f"{page['representation']['markdown']}")


def print_video_results(standard_output_result):
    print(f"Duration: {standard_output_result['metadata']['duration_millis']} ms")
    print(f"Summary: {standard_output_result['video']['summary']}")
    statistics = standard_output_result['statistics']
    print("Statistics:")
    print(f"- Speaket count: {statistics['speaker_count']}")
    print(f"- Chapter count: {statistics['chapter_count']}")
    print(f"- Shot count: {statistics['shot_count']}")
    for chapter in standard_output_result['chapters']:
        print(f"Chapter {chapter['chapter_index']} {chapter['start_timecode_smpte']}-{chapter['end_timecode_smpte']} ({chapter['duration_millis']} ms)")
        if 'summary' in chapter:
            print(f"- Chapter summary: {chapter['summary']}")


def print_custom_results(custom_output_result):
    matched_blueprint_name = custom_output_result['matched_blueprint']['name']
    log(custom_output_result)
    print('\n- Custom output')
    print(f"Matched blueprint: {matched_blueprint_name}  Confidence: {custom_output_result['matched_blueprint']['confidence']}")
    print(f"Document class: {custom_output_result['document_class']['type']}")
    if matched_blueprint_name == BLUEPRINT_NAME:
        print('\n- Fields')
        for field_with_group in BLUEPRINT_FIELDS:
            print_field(field_with_group, custom_output_result)


def print_results(job_metadata_s3_uri) -> None:
    job_metadata = get_json_object_from_s3_uri(job_metadata_s3_uri)
    log(job_metadata)

    for segment in job_metadata['output_metadata']:
        asset_id = segment['asset_id']
        print(f'\nAsset ID: {asset_id}')

        for segment_metadata in segment['segment_metadata']:
            # Standard output
            standard_output_path = segment_metadata['standard_output_path']
            standard_output_result = get_json_object_from_s3_uri(standard_output_path)
            log(standard_output_result)
            print('\n- Standard output')
            semantic_modality = standard_output_result['metadata']['semantic_modality']
            print(f"Semantic modality: {semantic_modality}")
            match semantic_modality:
                case 'DOCUMENT':
                    print_document_results(standard_output_result)
                case 'VIDEO':
                    print_video_results(standard_output_result)
            # Custom output
            if 'custom_output_status' in segment_metadata and segment_metadata['custom_output_status'] == 'MATCH':
                custom_output_path = segment_metadata['custom_output_path']
                custom_output_result = get_json_object_from_s3_uri(custom_output_path)
                print_custom_results(custom_output_result)


def print_field(field_with_group, custom_output_result) -> None:
    inference_result = custom_output_result['inference_result']
    explainability_info = custom_output_result['explainability_info'][0]
    if '/' in field_with_group:
        # For fields part of a group
        (group, field) = field_with_group.split('/')
        inference_result = inference_result[group]
        explainability_info = explainability_info[group]
    else:
        field = field_with_group
    value = inference_result[field]
    confidence = explainability_info[field]['confidence']
    print(f'{field}: {value or '<EMPTY>'}  Confidence: {confidence}')


def main() -> None:
    if len(sys.argv) < 2:
        print("Please provide a filename as command line argument")
        sys.exit(1)
      
    file_name = sys.argv[1]
    
    aws_account_id = get_aws_account_id()
    input_s3_uri = f"s3://{BUCKET_NAME}/{INPUT_PATH}/{file_name}" # File
    output_s3_uri = f"s3://{BUCKET_NAME}/{OUTPUT_PATH}" # Folder
    data_automation_arn = f"arn:aws:bedrock:{AWS_REGION}:{aws_account_id}:data-automation-project/{PROJECT_ID}"

    print(f"Invoking Bedrock Data Automation for '{file_name}'", end='', flush=True)

    data_automation_response = invoke_data_automation(input_s3_uri, output_s3_uri, data_automation_arn, aws_account_id)
    data_automation_status = wait_for_data_automation_to_complete(data_automation_response['invocationArn'])

    if data_automation_status['status'] == 'Success':
        job_metadata_s3_uri = data_automation_status['outputConfiguration']['s3Uri']
        print_results(job_metadata_s3_uri)


if __name__ == "__main__":
    main()

The initial configuration in the script includes the name of the S3 bucket to use in input and output, the location of the input file in the bucket, the output path for the results, the project ID to use to get custom output from Bedrock Data Automation, and the blueprint fields to show in output.

I run the script passing the name of the input file. In output, I see the information extracted by Bedrock Data Automation. The US-Driver-License is a match and the name and dates in the driver’s license are printed in output.

python bda-ga.py bda-drivers-license.jpeg

Invoking Bedrock Data Automation for 'bda-drivers-license.jpeg'................ Success

Asset ID: 0

- Standard output
Semantic modality: DOCUMENT
Number of pages: 1
- Page 0
NEW JERSEY

Motor Vehicle
 Commission

AUTO DRIVER LICENSE

Could DL M6454 64774 51685                      CLASS D
        DOB 01-01-1968
ISS 03-19-2019          EXP     01-01-2023
        MONTOYA RENEE MARIA 321 GOTHAM AVENUE TRENTON, NJ 08666 OF
        END NONE
        RESTR NONE
        SEX F HGT 5'-08" EYES HZL               ORGAN DONOR
        CM ST201907800000019 CHG                11.00

[SIGNATURE]


- Custom output
Matched blueprint: US-Driver-License-copy  Confidence: 1
Document class: US-drivers-licenses

- Fields
FIRST_NAME: RENEE  Confidence: 0.859375
MIDDLE_NAME: MARIA  Confidence: 0.83203125
LAST_NAME: MONTOYA  Confidence: 0.875
DATE_OF_BIRTH: 1968-01-01  Confidence: 0.890625
DATE_OF_ISSUE: 2019-03-19  Confidence: 0.79296875
EXPIRATION_DATE: 2023-01-01  Confidence: 0.93359375

As expected, I see in output the information I selected from the blueprint associated with the Bedrock Data Automation project.

Similarly, I run the same script on a video file from my colleague Mike Chambers. To keep the output small, I don’t print the full audio transcript or the text displayed in the video.

python bda.py mike-video.mp4
Invoking Bedrock Data Automation for 'mike-video.mp4'.......................................................................................................................................................................................................................................................................... Success

Asset ID: 0

- Standard output
Semantic modality: VIDEO
Duration: 810476 ms
Summary: In this comprehensive demonstration, a technical expert explores the capabilities and limitations of Large Language Models (LLMs) while showcasing a practical application using AWS services. He begins by addressing a common misconception about LLMs, explaining that while they possess general world knowledge from their training data, they lack current, real-time information unless connected to external data sources.

To illustrate this concept, he demonstrates an "Outfit Planner" application that provides clothing recommendations based on location and weather conditions. Using Brisbane, Australia as an example, the application combines LLM capabilities with real-time weather data to suggest appropriate attire like lightweight linen shirts, shorts, and hats for the tropical climate.

The demonstration then shifts to the Amazon Bedrock platform, which enables users to build and scale generative AI applications using foundation models. The speaker showcases the "OutfitAssistantAgent," explaining how it accesses real-time weather data to make informed clothing recommendations. Through the platform's "Show Trace" feature, he reveals the agent's decision-making process and how it retrieves and processes location and weather information.

The technical implementation details are explored as the speaker configures the OutfitAssistant using Amazon Bedrock. The agent's workflow is designed to be fully serverless and managed within the Amazon Bedrock service.

Further diving into the technical aspects, the presentation covers the AWS Lambda console integration, showing how to create action group functions that connect to external services like the OpenWeatherMap API. The speaker emphasizes that LLMs become truly useful when connected to tools providing relevant data sources, whether databases, text files, or external APIs.

The presentation concludes with the speaker encouraging viewers to explore more AWS developer content and engage with the channel through likes and subscriptions, reinforcing the practical value of combining LLMs with external data sources for creating powerful, context-aware applications.
Statistics:
- Speaket count: 1
- Chapter count: 6
- Shot count: 48
Chapter 0 00:00:00:00-00:01:32:01 (92025 ms)
- Chapter summary: A man with a beard and glasses, wearing a gray hooded sweatshirt with various logos and text, is sitting at a desk in front of a colorful background. He discusses the frequent release of new large language models (LLMs) and how people often test these models by asking questions like "Who won the World Series?" The man explains that LLMs are trained on general data from the internet, so they may have information about past events but not current ones. He then poses the question of what he wants from an LLM, stating that he desires general world knowledge, such as understanding basic concepts like "up is up" and "down is down," but does not need specific factual knowledge. The man suggests that he can attach other systems to the LLM to access current factual data relevant to his needs. He emphasizes the importance of having general world knowledge and the ability to use tools and be linked into agentic workflows, which he refers to as "agentic workflows." The man encourages the audience to add this term to their spell checkers, as it will likely become commonly used.
Chapter 1 00:01:32:01-00:03:38:18 (126560 ms)
- Chapter summary: The video showcases a man with a beard and glasses demonstrating an "Outfit Planner" application on his laptop. The application allows users to input their location, such as Brisbane, Australia, and receive recommendations for appropriate outfits based on the weather conditions. The man explains that the application generates these recommendations using large language models, which can sometimes provide inaccurate or hallucinated information since they lack direct access to real-world data sources.

The man walks through the process of using the Outfit Planner, entering Brisbane as the location and receiving weather details like temperature, humidity, and cloud cover. He then shows how the application suggests outfit options, including a lightweight linen shirt, shorts, sandals, and a hat, along with an image of a woman wearing a similar outfit in a tropical setting.

Throughout the demonstration, the man points out the limitations of current language models in providing accurate and up-to-date information without external data connections. He also highlights the need to edit prompts and adjust settings within the application to refine the output and improve the accuracy of the generated recommendations.
Chapter 2 00:03:38:18-00:07:19:06 (220620 ms)
- Chapter summary: The video demonstrates the Amazon Bedrock platform, which allows users to build and scale generative AI applications using foundation models (FMs). [speaker_0] introduces the platform's overview, highlighting its key features like managing FMs from AWS, integrating with custom models, and providing access to leading AI startups. The video showcases the Amazon Bedrock console interface, where [speaker_0] navigates to the "Agents" section and selects the "OutfitAssistantAgent" agent. [speaker_0] tests the OutfitAssistantAgent by asking it for outfit recommendations in Brisbane, Australia. The agent provides a suggestion of wearing a light jacket or sweater due to cool, misty weather conditions. To verify the accuracy of the recommendation, [speaker_0] clicks on the "Show Trace" button, which reveals the agent's workflow and the steps it took to retrieve the current location details and weather information for Brisbane. The video explains that the agent uses an orchestration and knowledge base system to determine the appropriate response based on the user's query and the retrieved data. It highlights the agent's ability to access real-time information like location and weather data, which is crucial for generating accurate and relevant responses.
Chapter 3 00:07:19:06-00:11:26:13 (247214 ms)
- Chapter summary: The video demonstrates the process of configuring an AI assistant agent called "OutfitAssistant" using Amazon Bedrock. [speaker_0] introduces the agent's purpose, which is to provide outfit recommendations based on the current time and weather conditions. The configuration interface allows selecting a language model from Anthropic, in this case the Claud 3 Haiku model, and defining natural language instructions for the agent's behavior. [speaker_0] explains that action groups are groups of tools or actions that will interact with the outside world. The OutfitAssistant agent uses Lambda functions as its tools, making it fully serverless and managed within the Amazon Bedrock service. [speaker_0] defines two action groups: "get coordinates" to retrieve latitude and longitude coordinates from a place name, and "get current time" to determine the current time based on the location. The "get current weather" action requires calling the "get coordinates" action first to obtain the location coordinates, then using those coordinates to retrieve the current weather information. This demonstrates the agent's workflow and how it utilizes the defined actions to generate outfit recommendations. Throughout the video, [speaker_0] provides details on the agent's configuration, including its name, description, model selection, instructions, and action groups. The interface displays various options and settings related to these aspects, allowing [speaker_0] to customize the agent's behavior and functionality.
Chapter 4 00:11:26:13-00:13:00:17 (94160 ms)
- Chapter summary: The video showcases a presentation by [speaker_0] on the AWS Lambda console and its integration with machine learning models for building powerful agents. [speaker_0] demonstrates how to create an action group function using AWS Lambda, which can be used to generate text responses based on input parameters like location, time, and weather data. The Lambda function code is shown, utilizing external services like OpenWeatherMap API for fetching weather information. [speaker_0] explains that for a large language model to be useful, it needs to connect to tools providing relevant data sources, such as databases, text files, or external APIs. The presentation covers the process of defining actions, setting up Lambda functions, and leveraging various tools within the AWS environment to build intelligent agents capable of generating context-aware responses.
Chapter 5 00:13:00:17-00:13:28:10 (27761 ms)
- Chapter summary: A man with a beard and glasses, wearing a gray hoodie with various logos and text, is sitting at a desk in front of a colorful background. He is using a laptop computer that has stickers and logos on it, including the AWS logo. The man appears to be presenting or speaking about AWS (Amazon Web Services) and its services, such as Lambda functions and large language models. He mentions that if a Lambda function can do something, then it can be used to augment a large language model. The man concludes by expressing hope that the viewer found the video useful and insightful, and encourages them to check out other videos on the AWS developers channel. He also asks viewers to like the video, subscribe to the channel, and watch other videos.

Things to know
Amazon Bedrock Data Automation is now available via cross-region inference in the following two AWS Regions: US East (N. Virginia) and US West (Oregon). When using Bedrock Data Automation from those Regions, data can be processed using cross-region inference in any of these four Regions: US East (Ohio, N. Virginia) and US West (N. California, Oregon). All these Regions are in the US so that data is processed within the same geography. We’re working to add support for more Regions in Europe and Asia later in 2025.

There’s no change in pricing compared to the preview and when using cross-region inference. For more information, visit Amazon Bedrock pricing.

Bedrock Data Automation now also includes a number of security, governance and manageability related capabilities such as AWS Key Management Service (AWS KMS) customer managed keys support for granular encryption control, AWS PrivateLink to connect directly to the Bedrock Data Automation APIs in your virtual private cloud (VPC) instead of connecting over the internet, and tagging of Bedrock Data Automation resources and jobs to track costs and enforce tag-based access policies in AWS Identity and Access Management (IAM).

I used Python in this blog post but Bedrock Data Automation is available with any AWS SDKs. For example, you can use Java, .NET, or Rust for a backend document processing application; JavaScript for a web app that processes images, videos, or audio files; and Swift for a native mobile app that processes content provided by end users. It’s never been so easy to get insights from multimodal data.

Here are a few reading suggestions to learn more (including code samples):

Danilo

How is the News Blog doing? Take this 1 minute survey!