Tag Archives: news

Amazon S3 Tables integration with Amazon SageMaker Lakehouse is now generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-s3-tables-integration-with-amazon-sagemaker-lakehouse-is-now-generally-available/

At re:Invent 2024, we launched Amazon S3 Tables, the first cloud object store with built-in Apache Iceberg support to streamline storing tabular data at scale, and Amazon SageMaker Lakehouse to simplify analytics and AI with a unified, open, and secure data lakehouse. We also previewed S3 Tables integration with Amazon Web Services (AWS) analytics services for you to stream, query, and visualize S3 Tables data using Amazon Athena, Amazon Data Firehose, Amazon EMR, AWS Glue, Amazon Redshift, and Amazon QuickSight.

Our customers wanted to simplify the management and optimization of their Apache Iceberg storage, which led to the development of S3 Tables. They were simultaneously working to break down data silos that impede analytics collaboration and insight generation using the SageMaker Lakehouse. When paired with S3 Tables and SageMaker Lakehouse in addition to built-in integration with AWS analytics services, they can gain a comprehensive platform unifying access to multiple data sources enabling both analytics and machine learning (ML) workflows.

Today, we’re announcing the general availability of Amazon S3 Tables integration with Amazon SageMaker Lakehouse to provide unified S3 Tables data access across various analytics engines and tools. You can access SageMaker Lakehouse from Amazon SageMaker Unified Studio, a single data and AI development environment that brings together functionality and tools from AWS analytics and AI/ML services. All S3 tables data integrated with SageMaker Lakehouse can be queried from SageMaker Unified Studio and engines such as Amazon Athena, Amazon EMR, Amazon Redshift, and Apache Iceberg-compatible engines like Apache Spark or PyIceberg.

With this integration, you can simplify building secure analytic workflows where you can read and write to S3 Tables and join with data in Amazon Redshift data warehouses and third-party and federated data sources, such as Amazon DynamoDB or PostgreSQL.

You can also centrally set up and manage fine-grained access permissions on the data in S3 Tables along with other data in the SageMaker Lakehouse and consistently apply them across all analytics and query engines.

S3 Tables integration with SageMaker Lakehouse in action
To get started, go to the Amazon S3 console and choose Table buckets from the navigation pane and select Enable integration to access table buckets from AWS analytics services.

Now you can create your table bucket to integrate with SageMaker Lakehouse. To learn more, visit Getting started with S3 Tables in the AWS documentation.

1. Create a table with Amazon Athena in the Amazon S3 console
You can create a table, populate it with data, and query it directly from the Amazon S3 console using Amazon Athena with just a few steps. Select a table bucket and select Create table with Athena, or you can select an existing table and select Query table with Athena.

2. Create tables with Athena

When you want to create a table with Athena, you should first specify a namespace for your table. The namespace in an S3 table bucket is equivalent to a database in AWS Glue, and you use the table namespace as the database in your Athena queries.

Choose a namespace and select Create table with Athena. It goes to the Query editor in the Athena console. You can create a table in your S3 table bucket or query data in the table.

2. Query with Athena

2. Query with SageMaker Lakehouse in the SageMaker Unified Studio
Now you can access unified data across S3 data lakes, Redshift data warehouses, third-party and federated data sources in SageMaker Lakehouse directly from SageMaker Unified Studio.

To get started, go to the SageMaker console and create a SageMaker Unified Studio domain and project using a sample project profile: Data Analytics and AI-ML model development. To learn more, visit Create an Amazon SageMaker Unified Studio domain in the AWS documentation.

After the project is created, navigate to the project overview and scroll down to project details to note down the project role Amazon Resource Name (ARN).

3. Project details in SageMaker Unified Studio

Go to the AWS Lake Formation console and grant permissions for AWS Identity and Access Management (IAM) users and roles. In the in the Principals section, select the <project role ARN> noted in the previous paragraph. Choose Named Data Catalog resources in the LF-Tags or catalog resources section and select the table bucket name you created for Catalogs. To learn more, visit Overview of Lake Formation permissions in the AWS documentation.

4. Grant permissions in Lake Formation console

When you return to SageMaker Unified Studio, you can see your table bucket project under Lakehouse in the Data menu in the left navigation pane of project page. When you choose Actions, you can select how to query your table bucket data in Amazon Athena, Amazon Redshift, or JupyterLab Notebook.

5. S3 Tables in Unified Studio

When you choose Query with Athena, it automatically goes to Query Editor to run data query language (DQL) and data manipulation language (DML) queries on S3 tables using Athena.

Here is a sample query using Athena:

select * from "s3tablecatalog/s3tables-integblog-bucket”.”proddb"."customer" limit 10;

6. Athena query in Unified Studio

To query with Amazon Redshift, you should set up Amazon Redshift Serverless compute resources for data query analysis. And then you choose Query with Redshift and run SQL in the Query Editor. If you want to use JupyterLab Notebook, you should create a new JupyterLab space in Amazon EMR Serverless.

3. Join data from other sources with S3 Tables data
With S3 Tables data now available in SageMaker Lakehouse, you can join it with data from data warehouses, online transaction processing (OLTP) sources like relational or non-relational database, Iceberg tables, and other third party sources to gain more comprehensive and deeper insights.

For example, you can add connections to data sources such as Amazon DocumentDB, Amazon DynamoDB, Amazon Redshift, PostgreSQL, MySQL, Google BigQuery, or Snowflake and combine data using SQL without extract, transform, and load (ETL) scripts.

Now you can run the SQL query in the Query editor to join the data in the S3 Tables with the data in the DynamoDB.

Here is a sample query to join between Athena and DynamoDB:

select * from "s3tablescatalog/s3tables-integblog-bucket"."blogdb"."customer", 
              "dynamodb1"."default"."customer_ddb" where cust_id=pid limit 10;

To learn more about this integration, visit Amazon S3 Tables integration with Amazon SageMaker Lakehouse in the AWS documentation.

Now available
S3 Tables integration with SageMaker Lakehouse is now generally available in all AWS Regions where S3 Tables are available. To learn more, visit the S3 Tables product page and the SageMaker Lakehouse page.

Give S3 Tables a try in the SageMaker Unified Studio today and send feedback to AWS re:Post for Amazon S3 and AWS re:Post for Amazon SageMaker or through your usual AWS Support contacts.

In the annual celebration of the launch of Amazon S3, we will introduce more awesome launches for Amazon S3 and Amazon SageMaker. To learn more, join the AWS Pi Day event on March 14.

— Channy

—

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

DeepSeek-R1 now available as a fully managed serverless model in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-r1-now-available-as-a-fully-managed-serverless-model-in-amazon-bedrock/

As of January 30, DeepSeek-R1 models became available in Amazon Bedrock through the Amazon Bedrock Marketplace and Amazon Bedrock Custom Model Import. Since then, thousands of customers have deployed these models in Amazon Bedrock. Customers value the robust guardrails and comprehensive tooling for safe AI deployment. Today, we’re making it even easier to use DeepSeek in Amazon Bedrock through an expanded range of options, including a new serverless solution.

The fully managed DeepSeek-R1 model is now generally available in Amazon Bedrock. Amazon Web Services (AWS) is the first cloud service provider (CSP) to deliver DeepSeek-R1 as a fully managed, generally available model. You can accelerate innovation and deliver tangible business value with DeepSeek on AWS without having to manage infrastructure complexities. You can power your generative AI applications with DeepSeek-R1’s capabilities using a single API in the Amazon Bedrock’s fully managed service and get the benefit of its extensive features and tooling.

According to DeepSeek, their model is publicly available under MIT license and offers strong capabilities in reasoning, coding, and natural language understanding. These capabilities power intelligent decision support, software development, mathematical problem-solving, scientific analysis, data insights, and comprehensive knowledge management systems.

As is the case for all AI solutions, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results. When implementing publicly available models like DeepSeek-R1, consider the following:

  • Data security – You can access the enterprise-grade security, monitoring, and cost control features of Amazon Bedrock that are essential for deploying AI responsibly at scale, all while retaining complete control over your data. Users’ inputs and model outputs aren’t shared with any model providers. You can use these key security features by default, including data encryption at rest and in transit, fine-grained access controls, secure connectivity options, and download various compliance certifications while communicating with the DeepSeek-R1 model in Amazon Bedrock.
  • Responsible AI – You can implement safeguards customized to your application requirements and responsible AI policies with Amazon Bedrock Guardrails. This includes key features of content filtering, sensitive information filtering, and customizable security controls to prevent hallucinations using contextual grounding and Automated Reasoning checks. This means you can control the interaction between users and the DeepSeek-R1 model in Bedrock with your defined set of policies by filtering undesirable and harmful content in your generative AI applications.
  • Model evaluation – You can evaluate and compare models to identify the optimal model for your use case, including DeepSeek-R1, in a few steps through either automatic or human evaluations by using Amazon Bedrock model evaluation tools. You can choose automatic evaluation with predefined metrics such as accuracy, robustness, and toxicity. Alternatively, you can choose human evaluation workflows for subjective or custom metrics such as relevance, style, and alignment to brand voice. Model evaluation provides built-in curated datasets, or you can bring in your own datasets.

We strongly recommend integrating Amazon Bedrock Guardrails and using Amazon Bedrock model evaluation features with your DeepSeek-R1 model to add robust protection for your generative AI applications. To learn more, visit Protect your DeepSeek model deployments with Amazon Bedrock Guardrails and Evaluate the performance of Amazon Bedrock resources.

Get started with the DeepSeek-R1 model in Amazon Bedrock
If you’re new to using DeepSeek-R1 models, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-R1 model, request access for DeepSeek-R1 in DeepSeek. You’ll then be granted access to the model in Amazon Bedrock.

Next, to test the DeepSeek-R1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-R1 as the model. Then choose Apply.

Using the selected DeepSeek-R1 model, I run the following prompt example:

A family has $5,000 to save for their vacation next year. They can place the money in a savings account earning 2% interest annually or in a certificate of deposit earning 4% interest annually but with no access to the funds until the vacation. If they need $1,000 for emergency expenses during the year, how should they divide their money between the two options to maximize their vacation fund?

This prompt requires a complex chain of thought and produces very precise reasoning results.

To learn more about usage recommendations for prompts, refer to the README of the DeepSeek-R1 model in its GitHub repository.

By choosing View API request, you can also access the model using code examples in the AWS Command Line Interface (AWS CLI) and AWS SDK. You can use us.deepseek.r1-v1:0 as the model ID.

Here is a sample of the AWS CLI command:

aws bedrock-runtime invoke-model \
     --model-id us.deepseek-r1-v1:0 \
     --body "{\"messages\":[{\"role\":\"user\",\"content\":[{\"type\":\"text\",\"text\":\"[n\"}]}],max_tokens\":2000,\"temperature\":0.6,\"top_k\":250,\"top_p\":0.9,\"stop_sequences\":[\"\\n\\nHuman:\"]}" \
     --cli-binary-format raw-in-base64-out \
     --region us-west-2 \
     invoke-model-output.txt

The model supports both the InvokeModel and Converse API. The following Python code examples show how to send a text message to the DeepSeek-R1 model using the Amazon Bedrock Converse API for text generation.

import boto3
from botocore.exceptions import ClientError

# Create a Bedrock Runtime client in the AWS Region you want to use.
client = boto3.client("bedrock-runtime", region_name="us-west-2")

# Set the model ID, e.g., Llama 3 8b Instruct.
model_id = "us.deepseek.r1-v1:0"

# Start a conversation with the user message.
user_message = "Describe the purpose of a 'hello world' program in one line."
conversation = [
    {
        "role": "user",
        "content": [{"text": user_message}],
    }
]

try:
    # Send the message to the model, using a basic inference configuration.
    response = client.converse(
        modelId=model_id,
        messages=conversation,
        inferenceConfig={"maxTokens": 2000, "temperature": 0.6, "topP": 0.9},
    )

    # Extract and print the response text.
    response_text = response["output"]["message"]["content"][0]["text"]
    print(response_text)

except (ClientError, Exception) as e:
    print(f"ERROR: Can't invoke '{model_id}'. Reason: {e}")
    exit(1)

To enable Amazon Bedrock Guardrails on the DeepSeek-R1 model, select Guardrails under Safeguards in the left navigation pane, and create a guardrail by configuring as many filters as you need. For example, if you filter for “politics” word, your guardrails will recognize this word in the prompt and show you the blocked message.

4. Apply the Bedrock Guardrails to the DeepSeek-R1 model

You can test the guardrail with different inputs to assess the guardrail’s performance. You can refine the guardrail by setting denied topics, word filters, sensitive information filters, and blocked messaging until it matches your needs.

To learn more about Amazon Bedrock Guardrails, visit Stop harmful content in models using Amazon Bedrock Guardrails in the AWS documentation or other deep dive blog posts about Amazon Bedrock Guardrails on the AWS Machine Learning Blog channel.

Here’s a demo walkthrough highlighting how you can take advantage of the fully managed DeepSeek-R1 model in Amazon Bedrock:

Now available
DeepSeek-R1 is now available fully managed in Amazon Bedrock in the US East (N. Virginia), US East (Ohio), and US West (Oregon) AWS Regions through cross-Region inference. Check the full Region list for future updates. To learn more, check out the DeepSeek in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give the DeepSeek-R1 model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Updated on March 10, 2025 — Fixed a screenshot of model selection and model ID.

AWS Weekly Roundup: Amazon Q CLI agent, AWS Step Functions, AWS Lambda, and more (March 10, 2025)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-q-cli-agent-aws-step-functions-aws-lambda-and-more-march-10-2025/

As the weather improves in the Northern hemisphere, there are more opportunities to learn and connect. This week, I’ll be in San Francisco, and we can meet at the Nova Networking Night at the AWS GenAI Loft where we’ll dive into the world of Amazon Nova foundation models (FMs) with live demos and real-world implementations.

AWS Pi Day is now a yearly tradition. It started in 2021 as a celebration of the 15th anniversary of Amazon S3. This year, there will be in-depth discussions with AWS product teams on how to build a data foundation for a unified seamless experience, managing and using data for analytics and AI workloads. Join us online to learn about the latest innovations through hands-on demos, and ask questions during our interactive livestream.

Last week’s launches
Another busy week, here are the launches that got my attention.

Amazon Q Developer – You can now use an enhanced agent within the Amazon Q command line interface (CLI) to give you more dynamic conversations, help you read and write files locally, query AWS resources, or create code. This enhanced CLI agent is powered by Anthropic’s most intelligent model to date, Claude 3.7 Sonnet. Read more about this agenic coding experience and how to try it out. Here’s a visual demo of the new capabilities of Amazon Q CLI, by Nathan Peck.

Amazon Q Business – Now supports the ingestion of audio and video data. This capability streamlines information retrieval, enhances knowledge sharing, and improves decision-making processes, by making multimedia content as searchable and accessible as text-based documents.

Amazon Bedrock – Bedrock Data Automation is now generally available, so you can automate the generation of valuable insights from unstructured multimodal content such as documents, images, video, and audio files. Learn more and see code examples in my blog post. Amazon Bedrock Knowledge Bases support for GraphRAG is now also generally available. GraphRAG is a capability that enhances Retrieval-Augmented Generation (RAG) by incorporating graph data and delivers more comprehensive, relevant, and explainable responses by leveraging relationships within your data, improving how Generative AI applications retrieve and synthesize information.

Amazon Nova – The Amazon Nova Pro foundation model now supports latency-optimized inference in preview on Amazon Bedrock, enabling faster response times and improved responsiveness for generative AI applications.

AWS Step Functions – Workflow Studio for VS Code is now available, a visual builder you can use to compose workflows on a canvas. You can generate workflow definitions in the background to create workflows in your local development environment. Read more about this enhanced local IDE experience.

AWS Lambda – Now supports Amazon CloudWatch Logs Live Tail in VS Code. We previously introduced support for Live Tail in the Lambda console to simplify how you can view and analyze Lambda logs in real time. Now, you can also monitor Lambda function logs in real time while staying within the VS Code development environment.

AWS Amplify – Now supports HttpOnly cookies for server-rendered Next.js applications when using Amazon Cognito’s managed login. Because cookies with the HttpOnly attribute can’t be accessed by JavaScript, your applications can gain an additional layer of protection against cross-site scripting (XSS) attacks.

Amazon Cognito – You can now customize access tokens for machine-to-machine (M2M) flows, enabling you to implement fine-grained authorization in your applications, APIs, and workloads. M2M authorization is commonly used for automated processes such as scheduled data synchronization tasks, event-driven workflows, microservices communication, or real-time data streaming between systems.

AWS CodeBuild – Now supports builds on Linux x86, Arm, and Windows on-demand fleets directly on the host operating system without containerization. In this way, you can now execute build commands that require direct access to the host system resources or have specific requirements that make containerization challenging. For example, this is useful when building device drivers, running system-level tests, or working with tools that require host machine access. CodeBuild has also added support for Node 22, Python 3.13, and Go 1.23 in Linux x86, Arm, Windows, and macOS platforms.

Bottlerocket – The open source Linux-based operating system purpose-built for containers now supports NVIDIA’s Multi-Instance GPU (MIG) to help partition NVIDIA GPUs into multiple GPU instances on Kubernetes nodes and maximize GPU resource utilization. Bottlerocket now also supports AWS Neuron accelerated instance types and provides a default bootstrap container image that simplifies system setup tasks.

Amazon GameLift – Introducing Amazon GameLift Streams, a new managed capability that developers can use to stream games at up to 1080p resolution and 60 frames per second to any device with a WebRTC-enabled browser. To learn more, explore Donnie’s blog post.

Amazon FSx for NetApp ONTAP – Starting March 5, 2025, the SnapLock licensing fees for data stored in SnapLock volumes has been eliminated, making it more cost-effective.

Other AWS news
Here are some additional projects, blog posts, and news items that you might find interesting:

Accelerate AWS Well-Architected reviews with Generative AI – In this post, we explore a generative AI solution to streamline the Well-Architected Framework Reviews (WAFRs) process. We demonstrate how to build an intelligent, scalable system that analyzes architecture documents and generates insightful recommendations based on best practices.

Architectural diagram

Build a Multi-Agent System with LangGraph and Mistral on AWS – The Multi-Agent City Information System demonstrated in this post exemplifies the potential of agent-based architectures to create sophisticated, adaptable, and highly capable AI applications.

Reference architecture

Evaluate RAG responses with Amazon Bedrock, LlamaIndex and RAGAS – How to enhance your Retrieval Augmented Generation (RAG) implementations with practical techniques to evaluate and optimize your AI systems and enable more accurate, context-aware responses that align with your specific needs.

Architectural diagram

From community.aws
Here are some of my favorite posts from community.aws. Create your AWS Builder ID to start sharing your tips and connect with fellow builders. Your Builder ID is a universal login credential that gives you access, beyond the AWS Management Console, to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

Optimize AWS Lambda Costs with Automated Compute Optimizer Insights (Zechariah Kasina) – An automated and scalable method for optimizing AWS Lambda memory configurations to enhance cost efficiency and performance.

Optimize AWS Costs: Auto-Shutdown for EC2 Instances (Adeleke Adebowale Julius) – Using Amazon CloudWatch alarms to dynamically shut down instances based on inactivity.

The Evolution of the Developer Role in an AI-Assisted Future (Aaron Sempf) – While AI is transforming software development, the need for developing talent remains crucial.

Amazon Q Developer CLI – More coffee, less remembering commands (Cobus Bernard) – Now that you can use Amazon Q Developer directly from your terminal to interact with your files, so let’s add some convenience automations.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czech Republic (April 29).

AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations. Available in multiple geographic regions: North America (March 13), Greater China Region (March 14), and Latin America (April 8).

AWS Summits – The AWS Summit season is coming along! Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS re:Inforce (June 16–18) – Our annual learning event devoted to all things AWS Cloud security. This year is in Philadelphia, PA. Registration opens in March, so be ready to join more than 5,000 security builders and leaders.

AWS DevDays are free, technical events where developers can learn about some of the hottest topics in cloud computing. DevDays offer hands-on workshops, technical sessions, live demos, and networking with AWS technical experts and your peers. Register to access AWS DevDays sessions on demand.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Danilo

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

—

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Scale and deliver game streaming experiences with Amazon GameLift Streams

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/scale-and-deliver-game-streaming-experiences-with-amazon-gamelift-streams/

Since 2016, game developers have been using Amazon GameLift to power games with dedicated, scalable server hosting capable of supporting 100M concurrent users (CCU) in a single game. Responding to customer requests for additional managed compute capabilities beyond game servers, we’re announcing Amazon GameLift Streams — a new capability in Amazon GameLift to help game publishers build and deliver global, direct-to-player game streaming experiences. As part of this announcement, existing capabilities in Amazon GameLift are now known as Amazon Gamelift Servers, continuing to serve hundreds of developers including industry leaders Ubisoft, Zynga, WB Games, and Meta.

Amazon GameLift Streams helps you deliver game streaming experiences at up to 1080p resolution and 60 frames per second across devices including iOS, Android, and PCs. In just a few clicks, you can deploy games built with a variety of 3D engines, without modifications, onto fully-managed cloud-based GPU instances and stream games through the AWS Network Backbone directly to any device with a web browser.

Amazon GameLift Streams helps you distribute your games direct-to-players, without having to invest millions of dollars in infrastructure and software development to build your own service. Players can start gaming in just a few seconds, without waiting for downloads or installs.

Here’s a quick look at Amazon GameLift Streams:

You can use the Amazon GameLift Streams SDK to integrate with your existing identity services, storefronts, game launchers, websites, or newly created experiences such as playable demos, and begin streaming to players. You can monitor active streams and usage from within the AWS console, and seamlessly scale your streaming infrastructure across multiple regions on the AWS global network to reach more players around the world with low-latency gameplay. Amazon GameLift Streams is the only solution that enables you to upload your game content onto fully-managed GPU instances in the cloud and start streaming in minutes, with little or no modification of your code.

Players can access AAA, AA, and indie games on PCs, phones, tablets, smart TVs, or any device with a WebRTC-enabled browser. Amazon GameLift Streams allows you to dynamically scale streaming capacity to match player demand, ensuring you only pay for what you need. You can choose from a selection of GPU instances that offer a range of price performance, and rely on the built-in security of AWS to protect your intellectual property.

Let’s get started
To begin using Amazon GameLift Streams, I need an existing Amazon GameLift Streams implementation. I prepare my game files by following the Amazon GameLift Streams documentation.

Then, I’ll upload my files to Amazon Simple Storage Service (Amazon S3). I can use the AWS Management Console or this AWS Command Line Interface (AWS CLI) command to upload my game files:

aws s3 sync my-game-folder s3://my-bucket/my-game-path

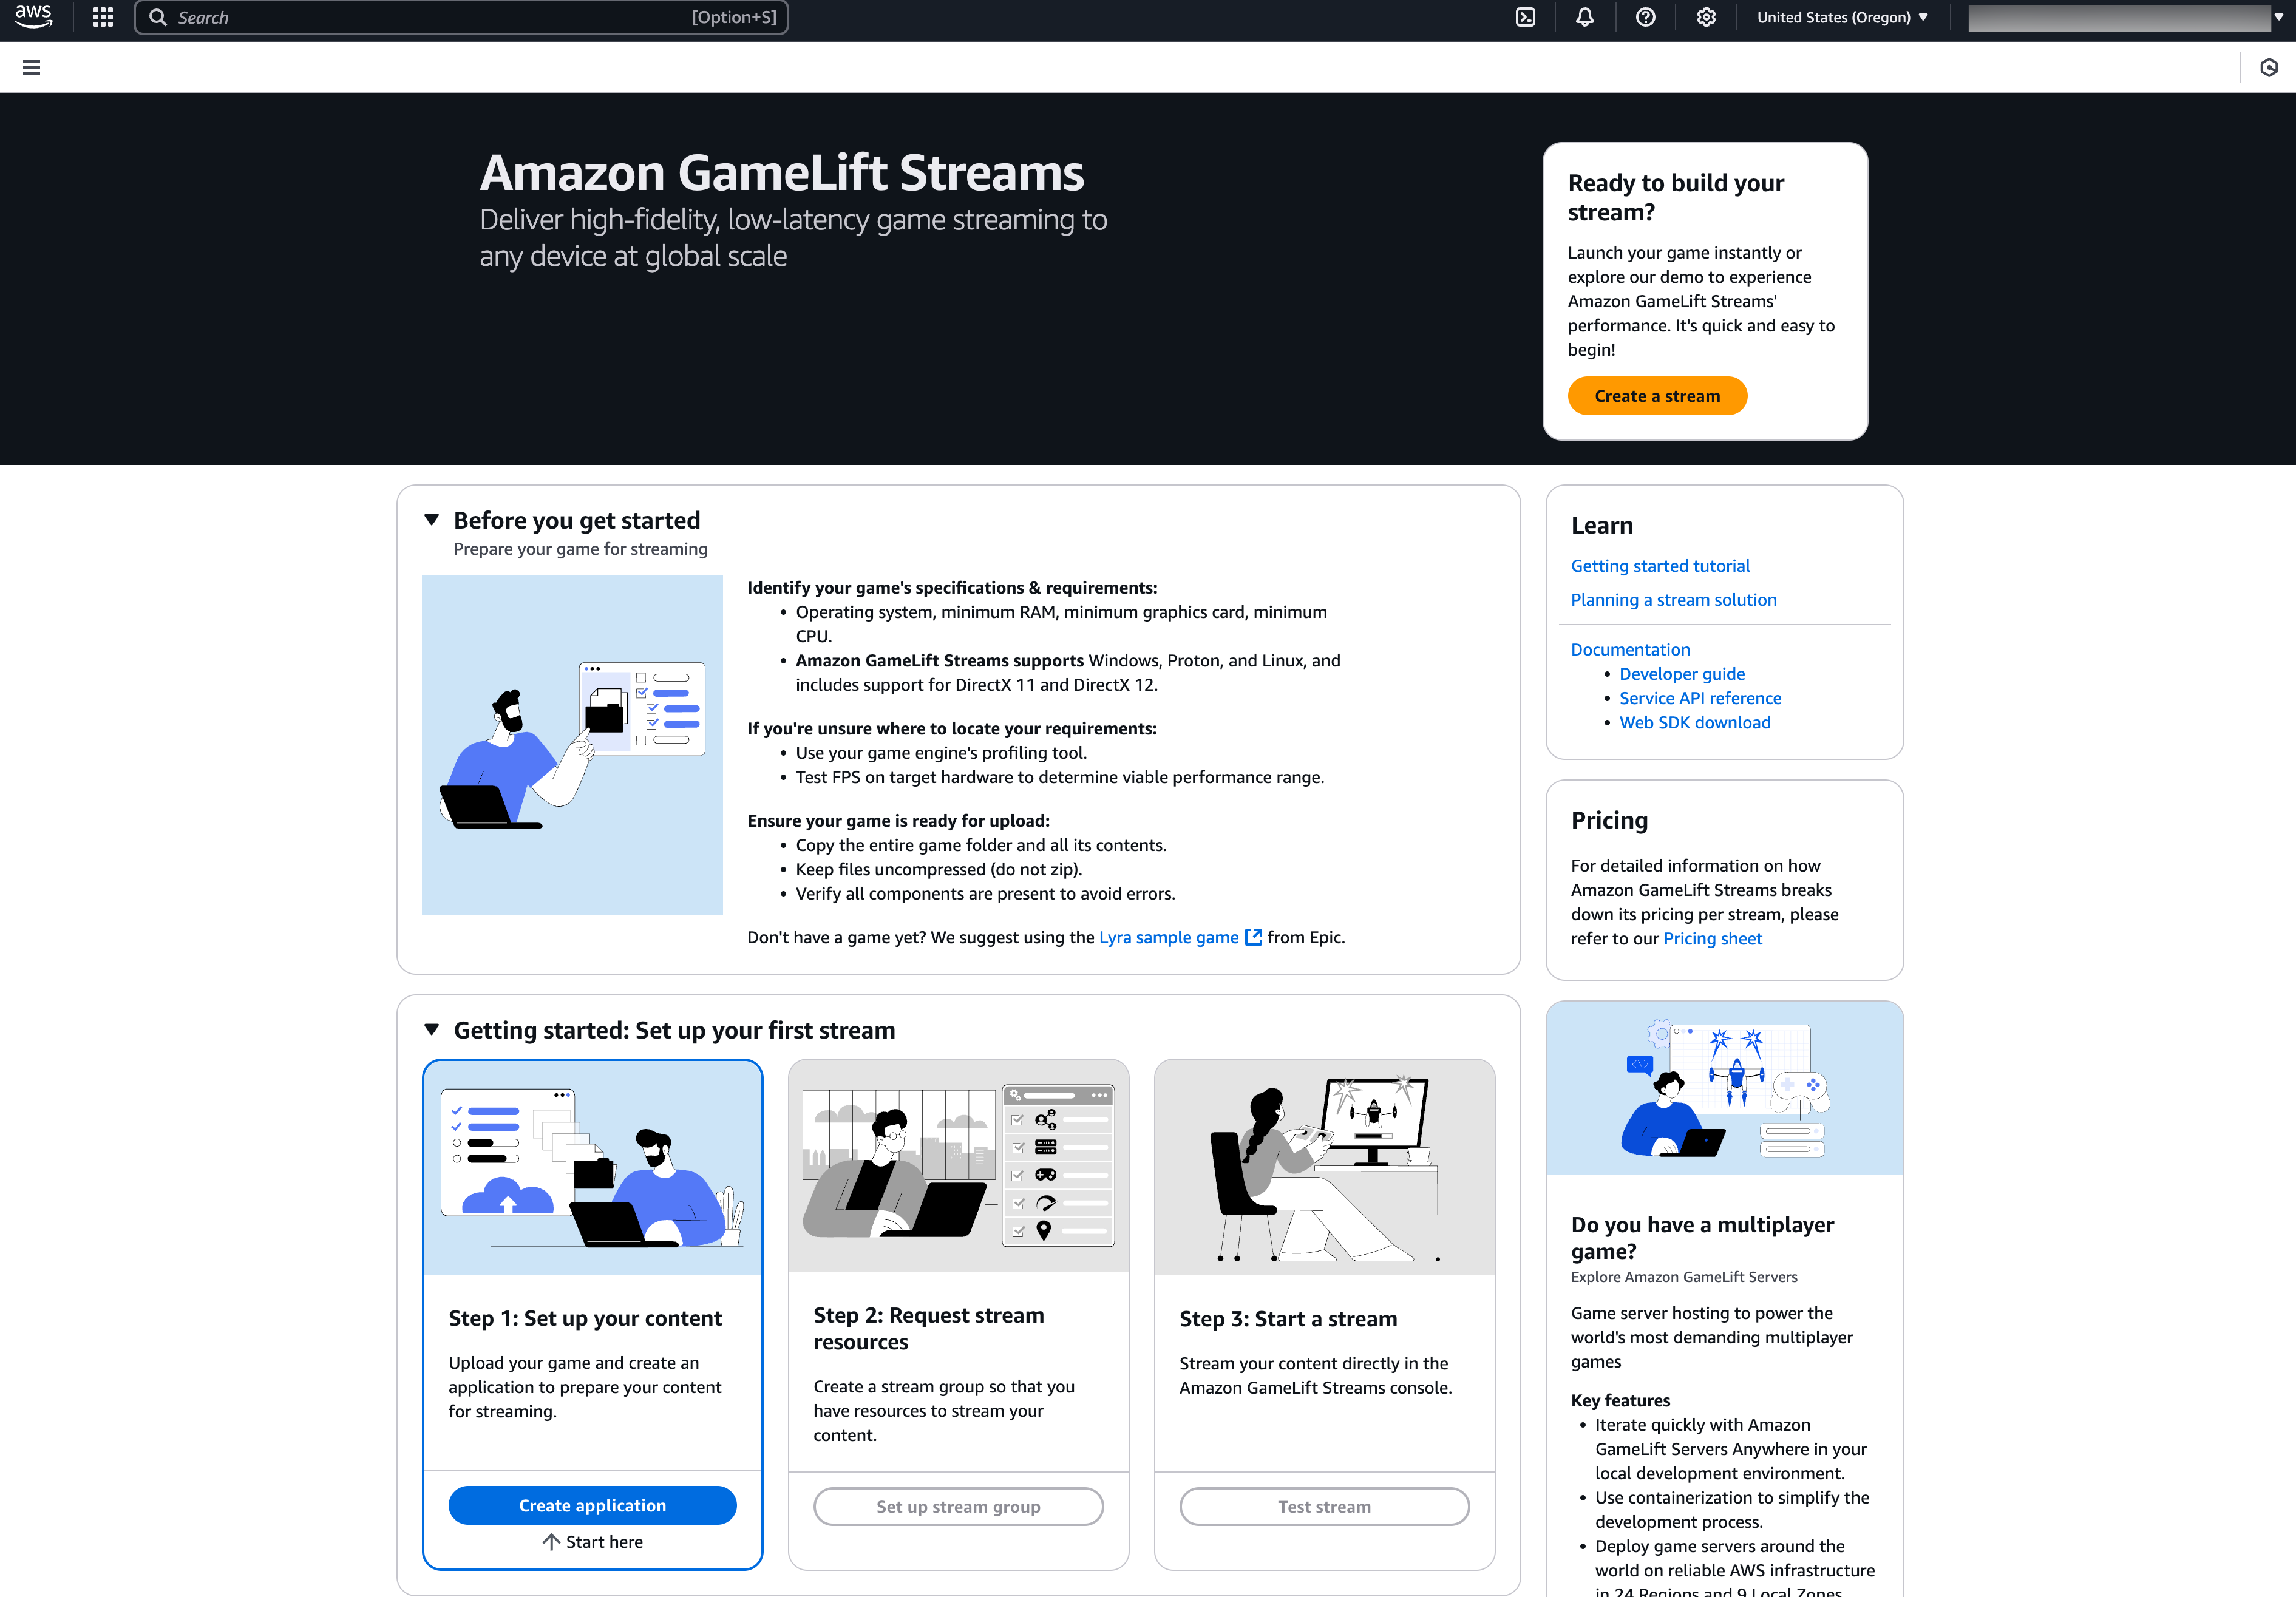
The next step is to create an Amazon GameLift Streams application. I navigate to the Amazon GameLift Streams console. This is how the new AWS GameLift Streams console looks:

On the Amazon GameLift Streams console, I choose Create application.

In the Runtime settings, I select the runtime environment for my game application.

Then, I need to select my S3 bucket and folder from the previous step, then set the path to my game’s main executable.

I also have the option to configure the automatic transfer of application-generated log files into a S3 bucket. After I’m done with this configuration, I choose Create application.

After my application setup is completed, I need to create a stream group, a collection of compute resources to run and stream the application. I navigate to Stream groups in the left navigation pane of the Amazon GameLift Streams console.

On this page, I define a description for my new stream group.

Here, I select the capabilities and pricing of my stream group. Since my application is using Microsoft Windows Server 2022 Base, I make sure to select one of the compatible stream classes.

Next, I need to link with the application I created in the previous step.

On the Configure stream settings page, I can configure additional locations for my stream group, bringing in additional capacity from other AWS Regions. There are two capacity options that I can choose, always-on capacity and on-demand capacity. The default capacity setting provides one streaming slot, which is sufficient for initial testing.

Then, I need to review my configuration and choose Create stream group.

With stream groups configured, I can test my game streaming. I navigate to the Test stream page on the console to launch my application as a stream. I select this stream group and select Choose.

On the next page, I can configure any command line arguments or environment variables to run my application. I don’t need any extra configurations and choose Test stream.

Then, I can see that my application is running as expected. I can also interact with my game. This test helps me verify that my game works properly in streaming mode and serves as an initial proof of concept.

After I’ve confirmed everything works, I can integrate the Web SDK into my own website. The Web SDK and AWS Software Development Kit (AWS SDK) with Amazon GameLift Streams APIs help me to embed game streams, similar to what I tested in the console, into any web page I manage.

Additional things to know

  • Availability – Amazon GameLift Streams is currently available in the following AWS Regions: US East (Ohio), US West (Oregon), Asia Pacific (Tokyo), Europe (Frankfurt). Additional streaming capacity can also be configured in US East (N. Virginia) and Europe (Ireland).
  • Supported operating systems – Amazon GameLift Streams supports games running on Windows, Linux, or Proton, offering easy onboarding and compatibility with game binaries. Learn more on Choosing a configuration in Amazon GameLift Streams documentation page.
  • Programmatic access – This new capability provides comprehensive tools including service APIs, client streaming SDKs, and AWS CLI for content packaging.

Now available
Explore how to streamline your game distribution using Amazon GameLift Streams. Learn more about getting started on the Amazon GameLift Streams page.

Happy streaming!

— Donnie

—

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

New year, new Heroes – March 2025

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/new-year-new-heroes-march-2025/

As we dive into 2025, we’re thrilled to announce our latest group of AWS Heroes! These exceptional individuals have demonstrated outstanding expertise and innovation, and are committed to sharing knowledge. Their contributions to the AWS community are greatly appreciated, and today we’re excited to celebrate them.

Ahmed Bebars – New Jersey, USA

Container Hero Ahmed Bebars is a Principal Engineer at The New York Times, where he leads the design and delivery of scalable developer platforms that enhance productivity and empower engineering teams. With deep expertise in containers, Kubernetes, and cloud-native technologies, Ahmed builds robust infrastructure solutions that streamline development workflows and support innovation. As an active member of the AWS and Cloud Native communities, he frequently shares his expertise at events like KubeCon, AWS re:Invent, AWS Community Days, and Kubernetes Community Days. Through his initiative, “Level Up with Ahmed,” he shares practical insights and resources to help engineers grow their skills and stay ahead in the evolving tech landscape.

Badri Narayanan Kesavan – Singapore

Community Hero Badri Narayanan Kesavan is an Engineering Lead and Solutions Architect with over a decade of professional experience, specializing in AWS Cloud solutions, platform engineering, and DevOps automation. Badri’s passion lies in learning and sharing with the community. He has delivered several talks at AWS Singapore Summit, AWS Summit ASEAN 2023, AWS Community Days, and various user group meetups. As an active AWS community leader, he organizes meetups and workshops under the AWS Singapore User Group where he regularly conducts sessions on diverse AWS topics, engaging a wide audience to foster innovation and collaboration. He has also authored the book “Mastering Amazon EC2)” which is a comprehensive guide to building robust and resilient applications on Amazon Elastic Compute Cloud (Amazon EC2).

Marcelo Paiva – Goiânia, Brazil

Community Hero Marcelo Paiva has over 30 years of experience in technology and is the CTO at Softprime Soluções, leading product development and research in digital biometrics, facial recognition, and artificial intelligence (AI). With more than a decade working with cloud computing, he specializes in building scalable and innovative solutions using AWS. Passionate about tech communities, Marcelo founded the AWS User Group in Goiânia in 2018, helping grow the local community. Today, he organizes events such as JoinCommunity and Cloud Summit Cerrado, fostering learning and networking in the Cerrado region.

Raphael Jambalos – Quezon City, Philippines

Community Hero Raphael Jambalos manages the Cloud Native development team at eCloudValley Philippines. His team has implemented dozens of cloud-native applications across multiple industries for customers in the Philippines. He is active in helping the AWS User Groups grow in the Philippines, and is passionate about connecting with the community beyond Manila. In his free time, he loves to read books and write about cloud technologies on his Dev.to blog.

Stav Ochakovski – Tel Aviv, Israel

Container Hero Stav Ochakovski is a DevOps Engineer at Beacon and a cybersecurity expert, managing highly scalable multi-cloud environments. With a background in DevOps engineering and instruction, Stav seamlessly transitioned into the dynamic cybersecurity start-up scene. A champion of container technologies and Amazon Elastic Kubernetes Service (Amazon EKS), she brings deep expertise in Kubernetes, CI/CD pipelines, and logging solutions to the AWS community. Stav actively shares her expertise by speaking at AWS community events, as well as security and container conferences. She is also a leader of the Israel AWS User Group and is a pastry-chef school graduate and licensed skipper.

Learn More

Visit the AWS Heroes website if you’d like to learn more about the AWS Heroes program, or to connect with a Hero near you.

— Taylor

Get insights from multimodal content with Amazon Bedrock Data Automation, now generally available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/get-insights-from-multimodal-content-with-amazon-bedrock-data-automation-now-generally-available/

Many applications need to interact with content available through different modalities. Some of these applications process complex documents, such as insurance claims and medical bills. Mobile apps need to analyze user-generated media. Organizations need to build a semantic index on top of their digital assets that include documents, images, audio, and video files. However, getting insights from unstructured multimodal content is not easy to set up: you have to implement processing pipelines for the different data formats and go through multiple steps to get the information you need. That usually means having multiple models in production for which you have to handle cost optimizations (through fine-tuning and prompt engineering), safeguards (for example, against hallucinations), integrations with the target applications (including data formats), and model updates.

To make this process easier, we introduced in preview during AWS re:Invent Amazon Bedrock Data Automation, a capability of Amazon Bedrock that streamlines the generation of valuable insights from unstructured, multimodal content such as documents, images, audio, and videos. With Bedrock Data Automation, you can reduce the development time and effort to build intelligent document processing, media analysis, and other multimodal data-centric automation solutions.

You can use Bedrock Data Automation as a standalone feature or as a parser for Amazon Bedrock Knowledge Bases to index insights from multimodal content and provide more relevant responses for Retrieval-Augmented Generation (RAG).

Today, Bedrock Data Automation is now generally available with support for cross-region inference endpoints to be available in more AWS Regions and seamlessly use compute across different locations. Based on your feedback during the preview, we also improved accuracy and added support for logo recognition for images and videos.

Let’s have a look at how this works in practice.

Using Amazon Bedrock Data Automation with cross-region inference endpoints
The blog post published for the Bedrock Data Automation preview shows how to use the visual demo in the Amazon Bedrock console to extract information from documents and videos. I recommend you go through the console demo experience to understand how this capability works and what you can do to customize it. For this post, I focus more on how Bedrock Data Automation works in your applications, starting with a few steps in the console and following with code samples.

The Data Automation section of the Amazon Bedrock console now asks for confirmation to enable cross-region support the first time you access it. For example:

Console screenshot.

From an API perspective, the InvokeDataAutomationAsync operation now requires an additional parameter (dataAutomationProfileArn) to specify the data automation profile to use. The value for this parameter depends on the Region and your AWS account ID:

arn:aws:bedrock:<REGION>:<ACCOUNT_ID>:data-automation-profile/us.data-automation-v1

Also, the dataAutomationArn parameter has been renamed to dataAutomationProjectArn to better reflect that it contains the project Amazon Resource Name (ARN). When invoking Bedrock Data Automation, you now need to specify a project or a blueprint to use. If you pass in blueprints, you will get custom output. To continue to get standard default output, configure the parameter DataAutomationProjectArn to use arn:aws:bedrock:<REGION>:aws:data-automation-project/public-default.

As the name suggests, the InvokeDataAutomationAsync operation is asynchronous. You pass the input and output configuration and, when the result is ready, it’s written on an Amazon Simple Storage Service (Amazon S3) bucket as specified in the output configuration. You can receive an Amazon EventBridge notification from Bedrock Data Automation using the notificationConfiguration parameter.

With Bedrock Data Automation, you can configure outputs in two ways:

  • Standard output delivers predefined insights relevant to a data type, such as document semantics, video chapter summaries, and audio transcripts. With standard outputs, you can set up your desired insights in just a few steps.
  • Custom output lets you specify extraction needs using blueprints for more tailored insights.

To see the new capabilities in action, I create a project and customize the standard output settings. For documents, I choose plain text instead of markdown. Note that you can automate these configuration steps using the Bedrock Data Automation API.

Console screenshot.

For videos, I want a full audio transcript and a summary of the entire video. I also ask for a summary of each chapter.

Console screenshot.

To configure a blueprint, I choose Custom output setup in the Data automation section of the Amazon Bedrock console navigation pane. There, I search for the US-Driver-License sample blueprint. You can browse other sample blueprints for more examples and ideas.

Sample blueprints can’t be edited, so I use the Actions menu to duplicate the blueprint and add it to my project. There, I can fine-tune the data to be extracted by modifying the blueprint and adding custom fields that can use generative AI to extract or compute data in the format I need.

Console screenshot.

I upload the image of a US driver’s license on an S3 bucket. Then, I use this sample Python script that uses Bedrock Data Automation through the AWS SDK for Python (Boto3) to extract text information from the image:

import json
import sys
import time

import boto3

DEBUG = False

AWS_REGION = '<REGION>'
BUCKET_NAME = '<BUCKET>'
INPUT_PATH = 'BDA/Input'
OUTPUT_PATH = 'BDA/Output'

PROJECT_ID = '<PROJECT_ID>'
BLUEPRINT_NAME = 'US-Driver-License-demo'

# Fields to display
BLUEPRINT_FIELDS = [
    'NAME_DETAILS/FIRST_NAME',
    'NAME_DETAILS/MIDDLE_NAME',
    'NAME_DETAILS/LAST_NAME',
    'DATE_OF_BIRTH',
    'DATE_OF_ISSUE',
    'EXPIRATION_DATE'
]

# AWS SDK for Python (Boto3) clients
bda = boto3.client('bedrock-data-automation-runtime', region_name=AWS_REGION)
s3 = boto3.client('s3', region_name=AWS_REGION)
sts = boto3.client('sts')


def log(data):
    if DEBUG:
        if type(data) is dict:
            text = json.dumps(data, indent=4)
        else:
            text = str(data)
        print(text)

def get_aws_account_id() -> str:
    return sts.get_caller_identity().get('Account')


def get_json_object_from_s3_uri(s3_uri) -> dict:
    s3_uri_split = s3_uri.split('/')
    bucket = s3_uri_split[2]
    key = '/'.join(s3_uri_split[3:])
    object_content = s3.get_object(Bucket=bucket, Key=key)['Body'].read()
    return json.loads(object_content)


def invoke_data_automation(input_s3_uri, output_s3_uri, data_automation_arn, aws_account_id) -> dict:
    params = {
        'inputConfiguration': {
            's3Uri': input_s3_uri
        },
        'outputConfiguration': {
            's3Uri': output_s3_uri
        },
        'dataAutomationConfiguration': {
            'dataAutomationProjectArn': data_automation_arn
        },
        'dataAutomationProfileArn': f"arn:aws:bedrock:{AWS_REGION}:{aws_account_id}:data-automation-profile/us.data-automation-v1"
    }

    response = bda.invoke_data_automation_async(**params)
    log(response)

    return response

def wait_for_data_automation_to_complete(invocation_arn, loop_time_in_seconds=1) -> dict:
    while True:
        response = bda.get_data_automation_status(
            invocationArn=invocation_arn
        )
        status = response['status']
        if status not in ['Created', 'InProgress']:
            print(f" {status}")
            return response
        print(".", end='', flush=True)
        time.sleep(loop_time_in_seconds)


def print_document_results(standard_output_result):
    print(f"Number of pages: {standard_output_result['metadata']['number_of_pages']}")
    for page in standard_output_result['pages']:
        print(f"- Page {page['page_index']}")
        if 'text' in page['representation']:
            print(f"{page['representation']['text']}")
        if 'markdown' in page['representation']:
            print(f"{page['representation']['markdown']}")


def print_video_results(standard_output_result):
    print(f"Duration: {standard_output_result['metadata']['duration_millis']} ms")
    print(f"Summary: {standard_output_result['video']['summary']}")
    statistics = standard_output_result['statistics']
    print("Statistics:")
    print(f"- Speaket count: {statistics['speaker_count']}")
    print(f"- Chapter count: {statistics['chapter_count']}")
    print(f"- Shot count: {statistics['shot_count']}")
    for chapter in standard_output_result['chapters']:
        print(f"Chapter {chapter['chapter_index']} {chapter['start_timecode_smpte']}-{chapter['end_timecode_smpte']} ({chapter['duration_millis']} ms)")
        if 'summary' in chapter:
            print(f"- Chapter summary: {chapter['summary']}")


def print_custom_results(custom_output_result):
    matched_blueprint_name = custom_output_result['matched_blueprint']['name']
    log(custom_output_result)
    print('\n- Custom output')
    print(f"Matched blueprint: {matched_blueprint_name}  Confidence: {custom_output_result['matched_blueprint']['confidence']}")
    print(f"Document class: {custom_output_result['document_class']['type']}")
    if matched_blueprint_name == BLUEPRINT_NAME:
        print('\n- Fields')
        for field_with_group in BLUEPRINT_FIELDS:
            print_field(field_with_group, custom_output_result)


def print_results(job_metadata_s3_uri) -> None:
    job_metadata = get_json_object_from_s3_uri(job_metadata_s3_uri)
    log(job_metadata)

    for segment in job_metadata['output_metadata']:
        asset_id = segment['asset_id']
        print(f'\nAsset ID: {asset_id}')

        for segment_metadata in segment['segment_metadata']:
            # Standard output
            standard_output_path = segment_metadata['standard_output_path']
            standard_output_result = get_json_object_from_s3_uri(standard_output_path)
            log(standard_output_result)
            print('\n- Standard output')
            semantic_modality = standard_output_result['metadata']['semantic_modality']
            print(f"Semantic modality: {semantic_modality}")
            match semantic_modality:
                case 'DOCUMENT':
                    print_document_results(standard_output_result)
                case 'VIDEO':
                    print_video_results(standard_output_result)
            # Custom output
            if 'custom_output_status' in segment_metadata and segment_metadata['custom_output_status'] == 'MATCH':
                custom_output_path = segment_metadata['custom_output_path']
                custom_output_result = get_json_object_from_s3_uri(custom_output_path)
                print_custom_results(custom_output_result)


def print_field(field_with_group, custom_output_result) -> None:
    inference_result = custom_output_result['inference_result']
    explainability_info = custom_output_result['explainability_info'][0]
    if '/' in field_with_group:
        # For fields part of a group
        (group, field) = field_with_group.split('/')
        inference_result = inference_result[group]
        explainability_info = explainability_info[group]
    else:
        field = field_with_group
    value = inference_result[field]
    confidence = explainability_info[field]['confidence']
    print(f'{field}: {value or '<EMPTY>'}  Confidence: {confidence}')


def main() -> None:
    if len(sys.argv) < 2:
        print("Please provide a filename as command line argument")
        sys.exit(1)
      
    file_name = sys.argv[1]
    
    aws_account_id = get_aws_account_id()
    input_s3_uri = f"s3://{BUCKET_NAME}/{INPUT_PATH}/{file_name}" # File
    output_s3_uri = f"s3://{BUCKET_NAME}/{OUTPUT_PATH}" # Folder
    data_automation_arn = f"arn:aws:bedrock:{AWS_REGION}:{aws_account_id}:data-automation-project/{PROJECT_ID}"

    print(f"Invoking Bedrock Data Automation for '{file_name}'", end='', flush=True)

    data_automation_response = invoke_data_automation(input_s3_uri, output_s3_uri, data_automation_arn, aws_account_id)
    data_automation_status = wait_for_data_automation_to_complete(data_automation_response['invocationArn'])

    if data_automation_status['status'] == 'Success':
        job_metadata_s3_uri = data_automation_status['outputConfiguration']['s3Uri']
        print_results(job_metadata_s3_uri)


if __name__ == "__main__":
    main()

The initial configuration in the script includes the name of the S3 bucket to use in input and output, the location of the input file in the bucket, the output path for the results, the project ID to use to get custom output from Bedrock Data Automation, and the blueprint fields to show in output.

I run the script passing the name of the input file. In output, I see the information extracted by Bedrock Data Automation. The US-Driver-License is a match and the name and dates in the driver’s license are printed in output.

python bda-ga.py bda-drivers-license.jpeg

Invoking Bedrock Data Automation for 'bda-drivers-license.jpeg'................ Success

Asset ID: 0

- Standard output
Semantic modality: DOCUMENT
Number of pages: 1
- Page 0
NEW JERSEY

Motor Vehicle
 Commission

AUTO DRIVER LICENSE

Could DL M6454 64774 51685                      CLASS D
        DOB 01-01-1968
ISS 03-19-2019          EXP     01-01-2023
        MONTOYA RENEE MARIA 321 GOTHAM AVENUE TRENTON, NJ 08666 OF
        END NONE
        RESTR NONE
        SEX F HGT 5'-08" EYES HZL               ORGAN DONOR
        CM ST201907800000019 CHG                11.00

[SIGNATURE]


- Custom output
Matched blueprint: US-Driver-License-copy  Confidence: 1
Document class: US-drivers-licenses

- Fields
FIRST_NAME: RENEE  Confidence: 0.859375
MIDDLE_NAME: MARIA  Confidence: 0.83203125
LAST_NAME: MONTOYA  Confidence: 0.875
DATE_OF_BIRTH: 1968-01-01  Confidence: 0.890625
DATE_OF_ISSUE: 2019-03-19  Confidence: 0.79296875
EXPIRATION_DATE: 2023-01-01  Confidence: 0.93359375

As expected, I see in output the information I selected from the blueprint associated with the Bedrock Data Automation project.

Similarly, I run the same script on a video file from my colleague Mike Chambers. To keep the output small, I don’t print the full audio transcript or the text displayed in the video.

python bda.py mike-video.mp4
Invoking Bedrock Data Automation for 'mike-video.mp4'.......................................................................................................................................................................................................................................................................... Success

Asset ID: 0

- Standard output
Semantic modality: VIDEO
Duration: 810476 ms
Summary: In this comprehensive demonstration, a technical expert explores the capabilities and limitations of Large Language Models (LLMs) while showcasing a practical application using AWS services. He begins by addressing a common misconception about LLMs, explaining that while they possess general world knowledge from their training data, they lack current, real-time information unless connected to external data sources.

To illustrate this concept, he demonstrates an "Outfit Planner" application that provides clothing recommendations based on location and weather conditions. Using Brisbane, Australia as an example, the application combines LLM capabilities with real-time weather data to suggest appropriate attire like lightweight linen shirts, shorts, and hats for the tropical climate.

The demonstration then shifts to the Amazon Bedrock platform, which enables users to build and scale generative AI applications using foundation models. The speaker showcases the "OutfitAssistantAgent," explaining how it accesses real-time weather data to make informed clothing recommendations. Through the platform's "Show Trace" feature, he reveals the agent's decision-making process and how it retrieves and processes location and weather information.

The technical implementation details are explored as the speaker configures the OutfitAssistant using Amazon Bedrock. The agent's workflow is designed to be fully serverless and managed within the Amazon Bedrock service.

Further diving into the technical aspects, the presentation covers the AWS Lambda console integration, showing how to create action group functions that connect to external services like the OpenWeatherMap API. The speaker emphasizes that LLMs become truly useful when connected to tools providing relevant data sources, whether databases, text files, or external APIs.

The presentation concludes with the speaker encouraging viewers to explore more AWS developer content and engage with the channel through likes and subscriptions, reinforcing the practical value of combining LLMs with external data sources for creating powerful, context-aware applications.
Statistics:
- Speaket count: 1
- Chapter count: 6
- Shot count: 48
Chapter 0 00:00:00:00-00:01:32:01 (92025 ms)
- Chapter summary: A man with a beard and glasses, wearing a gray hooded sweatshirt with various logos and text, is sitting at a desk in front of a colorful background. He discusses the frequent release of new large language models (LLMs) and how people often test these models by asking questions like "Who won the World Series?" The man explains that LLMs are trained on general data from the internet, so they may have information about past events but not current ones. He then poses the question of what he wants from an LLM, stating that he desires general world knowledge, such as understanding basic concepts like "up is up" and "down is down," but does not need specific factual knowledge. The man suggests that he can attach other systems to the LLM to access current factual data relevant to his needs. He emphasizes the importance of having general world knowledge and the ability to use tools and be linked into agentic workflows, which he refers to as "agentic workflows." The man encourages the audience to add this term to their spell checkers, as it will likely become commonly used.
Chapter 1 00:01:32:01-00:03:38:18 (126560 ms)
- Chapter summary: The video showcases a man with a beard and glasses demonstrating an "Outfit Planner" application on his laptop. The application allows users to input their location, such as Brisbane, Australia, and receive recommendations for appropriate outfits based on the weather conditions. The man explains that the application generates these recommendations using large language models, which can sometimes provide inaccurate or hallucinated information since they lack direct access to real-world data sources.

The man walks through the process of using the Outfit Planner, entering Brisbane as the location and receiving weather details like temperature, humidity, and cloud cover. He then shows how the application suggests outfit options, including a lightweight linen shirt, shorts, sandals, and a hat, along with an image of a woman wearing a similar outfit in a tropical setting.

Throughout the demonstration, the man points out the limitations of current language models in providing accurate and up-to-date information without external data connections. He also highlights the need to edit prompts and adjust settings within the application to refine the output and improve the accuracy of the generated recommendations.
Chapter 2 00:03:38:18-00:07:19:06 (220620 ms)
- Chapter summary: The video demonstrates the Amazon Bedrock platform, which allows users to build and scale generative AI applications using foundation models (FMs). [speaker_0] introduces the platform's overview, highlighting its key features like managing FMs from AWS, integrating with custom models, and providing access to leading AI startups. The video showcases the Amazon Bedrock console interface, where [speaker_0] navigates to the "Agents" section and selects the "OutfitAssistantAgent" agent. [speaker_0] tests the OutfitAssistantAgent by asking it for outfit recommendations in Brisbane, Australia. The agent provides a suggestion of wearing a light jacket or sweater due to cool, misty weather conditions. To verify the accuracy of the recommendation, [speaker_0] clicks on the "Show Trace" button, which reveals the agent's workflow and the steps it took to retrieve the current location details and weather information for Brisbane. The video explains that the agent uses an orchestration and knowledge base system to determine the appropriate response based on the user's query and the retrieved data. It highlights the agent's ability to access real-time information like location and weather data, which is crucial for generating accurate and relevant responses.
Chapter 3 00:07:19:06-00:11:26:13 (247214 ms)
- Chapter summary: The video demonstrates the process of configuring an AI assistant agent called "OutfitAssistant" using Amazon Bedrock. [speaker_0] introduces the agent's purpose, which is to provide outfit recommendations based on the current time and weather conditions. The configuration interface allows selecting a language model from Anthropic, in this case the Claud 3 Haiku model, and defining natural language instructions for the agent's behavior. [speaker_0] explains that action groups are groups of tools or actions that will interact with the outside world. The OutfitAssistant agent uses Lambda functions as its tools, making it fully serverless and managed within the Amazon Bedrock service. [speaker_0] defines two action groups: "get coordinates" to retrieve latitude and longitude coordinates from a place name, and "get current time" to determine the current time based on the location. The "get current weather" action requires calling the "get coordinates" action first to obtain the location coordinates, then using those coordinates to retrieve the current weather information. This demonstrates the agent's workflow and how it utilizes the defined actions to generate outfit recommendations. Throughout the video, [speaker_0] provides details on the agent's configuration, including its name, description, model selection, instructions, and action groups. The interface displays various options and settings related to these aspects, allowing [speaker_0] to customize the agent's behavior and functionality.
Chapter 4 00:11:26:13-00:13:00:17 (94160 ms)
- Chapter summary: The video showcases a presentation by [speaker_0] on the AWS Lambda console and its integration with machine learning models for building powerful agents. [speaker_0] demonstrates how to create an action group function using AWS Lambda, which can be used to generate text responses based on input parameters like location, time, and weather data. The Lambda function code is shown, utilizing external services like OpenWeatherMap API for fetching weather information. [speaker_0] explains that for a large language model to be useful, it needs to connect to tools providing relevant data sources, such as databases, text files, or external APIs. The presentation covers the process of defining actions, setting up Lambda functions, and leveraging various tools within the AWS environment to build intelligent agents capable of generating context-aware responses.
Chapter 5 00:13:00:17-00:13:28:10 (27761 ms)
- Chapter summary: A man with a beard and glasses, wearing a gray hoodie with various logos and text, is sitting at a desk in front of a colorful background. He is using a laptop computer that has stickers and logos on it, including the AWS logo. The man appears to be presenting or speaking about AWS (Amazon Web Services) and its services, such as Lambda functions and large language models. He mentions that if a Lambda function can do something, then it can be used to augment a large language model. The man concludes by expressing hope that the viewer found the video useful and insightful, and encourages them to check out other videos on the AWS developers channel. He also asks viewers to like the video, subscribe to the channel, and watch other videos.

Things to know
Amazon Bedrock Data Automation is now available via cross-region inference in the following two AWS Regions: US East (N. Virginia) and US West (Oregon). When using Bedrock Data Automation from those Regions, data can be processed using cross-region inference in any of these four Regions: US East (Ohio, N. Virginia) and US West (N. California, Oregon). All these Regions are in the US so that data is processed within the same geography. We’re working to add support for more Regions in Europe and Asia later in 2025.

There’s no change in pricing compared to the preview and when using cross-region inference. For more information, visit Amazon Bedrock pricing.

Bedrock Data Automation now also includes a number of security, governance and manageability related capabilities such as AWS Key Management Service (AWS KMS) customer managed keys support for granular encryption control, AWS PrivateLink to connect directly to the Bedrock Data Automation APIs in your virtual private cloud (VPC) instead of connecting over the internet, and tagging of Bedrock Data Automation resources and jobs to track costs and enforce tag-based access policies in AWS Identity and Access Management (IAM).

I used Python in this blog post but Bedrock Data Automation is available with any AWS SDKs. For example, you can use Java, .NET, or Rust for a backend document processing application; JavaScript for a web app that processes images, videos, or audio files; and Swift for a native mobile app that processes content provided by end users. It’s never been so easy to get insights from multimodal data.

Here are a few reading suggestions to learn more (including code samples):

– Danilo

—

How is the News Blog doing? Take this 1 minute survey!

AWS Weekly Roundup: Anthropic Claude 3.7, JAWS Days, cross-account access, and more (March 3, 2025)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-anthropic-claude-3-7-jaws-days-cross-account-access-and-more-march-3-2025/

I have fond memories of the time I built an application live at the AWS GenAI Loft London last September. AWS GenAI Lofts are back in locations such as San Francisco, Berlin, and more, to continue providing collaborative spaces and immersive experiences for startups and developers. Find a loft near you for hands-on access to AI products and services, events, workshops, and networking opportunities, that you can’t miss!

Last week’s launches
Here are some launches that got my attention during the previous week.

Four ways to grant cross-account access in AWS — For some situations, you might want to enable centralized operations across multiple AWS accounts or share resources across teams, or projects within your teams. In these cases, you may be concerned about security, availability, or the manageability of granting this cross-account access. We’ve announced four ways to grant cross-account access in AWS and detail each of the methods and its unique trade-offs.

Amazon ECS adds support for additional IAM condition keys — We’ve launched eight new service-specific condition keys for Identity and Access Management (IAM). These new condition keys let you create IAM policies as well as srvice control policies (SCPs) to better enforce your organizational policies in containerized environments. You can use IAM condition keys to author policies that enforce access control based on API request context.

AWS Chatbot is now named Amazon Q Developer — AWS Chatbot has been renamed to Amazon Q Developer, representing an enhancement to developer productivity through generative AI-powered capabilities. Furthermore, this update is an enhancement of our chat-based DevOps capabilities. By combining the proven functionality of AWS Chatbot with the generative AI capabilities of Amazon Q, we’re providing developers with more intuitive, efficient tools for cloud resource management.

Anthropic’s Claude 3.7 Sonnet hybrid reasoning model is now available in Amazon Bedrock — We’re expanding the foundation models (FM) offerings of Amazon Bedrock and we’ve announced the availability of Anthropic’s Claude 3.7 Sonnet FM in Amazon Bedrock. Claude 3.7 Sonnet is Anthropic’s most intelligent model to date. It stands out as their first hybrid reasoning model capable of producing quick responses or extended thinking, meaning it can work through difficult problems using careful, step-by-step reasoning.

Other AWS news
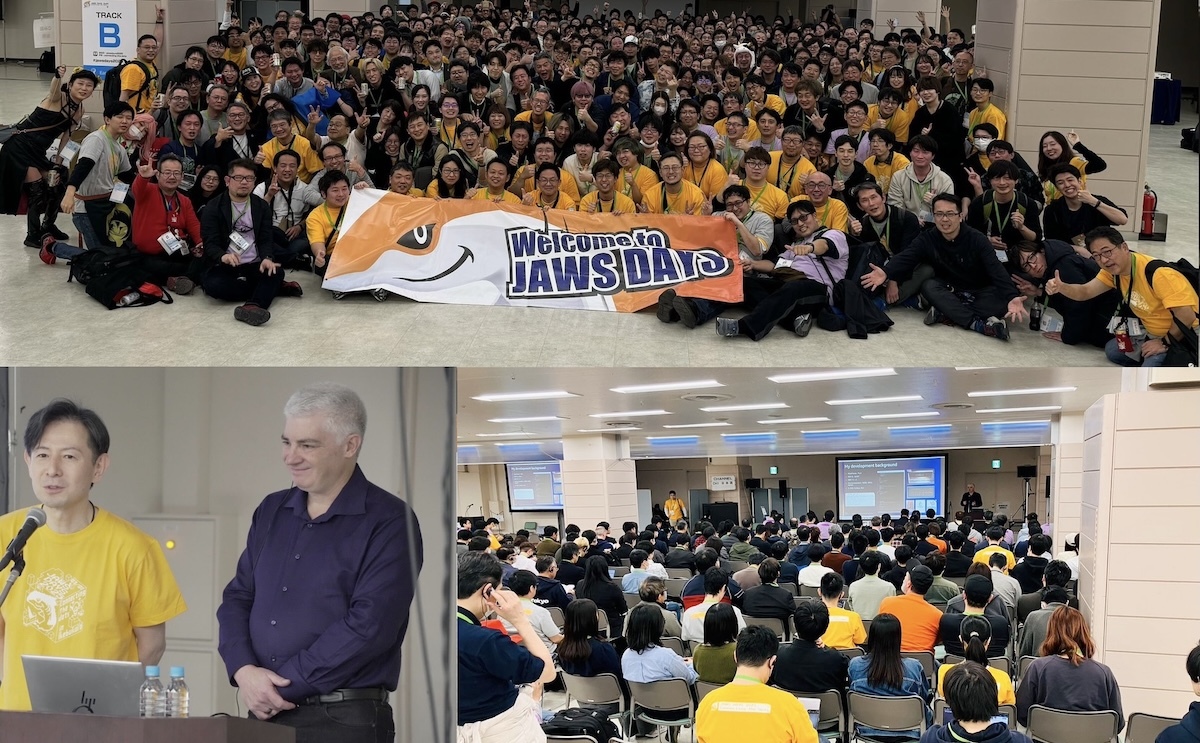
JAWS-UG (Japan AWS User Group) is the largest AWS user group in the world, and holds JAWS Days every year with over a thousand participants from Japan, Korea, Taiwan, and Hong Kong. The March 1st event started with a keynote speech on next-generation development by Jeff Barr (VP of AWS Evangelism), and included over 100 technical and community experience sessions, lightning talks, and workshops such as Game Days, Builders Card Challenges, and networking parties. If you want to experience the most active AWS community event in the world, I recommend attending next year.


Amazon Q Developer now generally available in Amazon SageMaker Canvas — Announced as available in preview at AWS reinvent 2024, Amazon Q Developer is now generally available in Amazon SageMaker Canvas to help you build machine learning (ML) models using natural language.

Applications for the 2025 AWS Cloud Club Captains Program are still open through March 6th. AWS Cloud Clubs are student-led groups for post-secondary and independent students, 18 years old and over. Find a club near you on the Meetup page.

From community.aws
Here are some of my favorite posts from community.aws:

DevSecOps on AWS: Secure, Automate, and Have a Laugh Along the Way – Discover how DevSecOps on AWS transforms your development pipeline by integrating security from the very first commit to production deployment, by Ahmed Mohamed.

Find out how to earn 100 percent free AWS certification vouchers in Opportunity to earn free AWS Certification Vouchers, published by Anand Joshi.

In the post, Boost SaaS Onboarding & Retention with AWS AI & Automation, Kaumudi Tiwari details how to navigate endless forms, generic guides, and a cluttered interface when signing up for a new software as a service (SaaS) platform.

My colleague Dennis Traub has published helpful step-by-step guides on how to use reasoning capabilities with Anthropic’s Claude 3.7 Sonnet in your C#/.NET, Java, JavaScript, or Python applications. Find these posts and much more generative AI-related content in the Gen AI Space on community.aws.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czech Republic (April 29).

AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations. Available in multiple geographic regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS re:Inforce – AWS re:Inforce (June 16–18) in Philadelphia, PA, is our annual learning event devoted to all things AWS Cloud security. Registration opens in March, so be ready to join more than 5,000 security builders and leaders.

AWS DevDays are free, technical events where developers can learn about some of the hottest topics in cloud computing. DevDays offer hands-on workshops, technical sessions, live demos, and networking with AWS technical experts and your peers. Register to access AWS DevDays sessions on demand.

Create your AWS Builder ID and reserve your alias. Builder ID is a universal login credential that gives you access—beyond the AWS Management Console—to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

AWS Training and Certification hosts free training events, both online and in-person, that help you get the most out of the AWS Cloud. Register to gain foundational cloud knowledge or dive deep in a technical area. Join AWS experts for training events that meet your goals, such as AWS Discovery Days, in-person. and virtual events at AWS Skills Centers including the one in Cape Town.

You can browse all upcoming in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Veliswa

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

—

How is the News Blog doing? Take this 1 minute survey!

NIS2 Requirement Support: The Zabbix Advantage

Post Syndicated from Michael Kammer original https://blog.zabbix.com/nis2-requirement-support-the-zabbix-advantage/29743/

In order to stay on top of a constantly-evolving cybersecurity landscape, the European Union has made the Network and Information Security (NIS2) Directive the cornerstone of their efforts to guarantee a uniform level of cybersecurity across all member states.

Introduced in 2020 and coming into effect on January 16, 2023, the NIS2 Directive is a continuation and expansion of NIS, the previous EU cybersecurity directive. NIS2 strengthens NIS, expands its scope, and introduces new requirements to help protect vital infrastructure, critical services, and key sectors from cyber threats.

In this post, we’ll go into detail about 8 key NIS2 requirements and see how Zabbix can help organizations meet each one.

NIS2 Requirement 1: Analyze risks and provide information system security.

Zabbix is set up to detect anomalies, suspicious activities, resource overload, downtime, and many other “red flags.” It can also monitor bandwidth usage and network interface metrics, and track the integrity of important files, including password and configuration files.

Monitoring critical services that prevent potential attacks (such as firewalls) is simple and intuitive, as is checking for open ports and insecure webpages. Not only that, Zabbix can track sensors in data centers to detect any physical security breaches and set up a customized alerting workflow for specific events.

NIS2 Requirement 2: Have procedures in place to handle security incidents as they arise.

Zabbix can provide real-time monitoring and alert users to potential incidents, keep a comprehensive log history for root cause analysis, and support multiple notification channels and scenarios for incident reporting. It can also share real-time incident data with external systems (via integrations or APIs) and display custom dashboards and reports about ongoing incidents.

NIS2 Requirement 3: Have backup management, disaster recovery, and crisis management plans in place to provide business continuity.

Zabbix supports Veeam (OOB) and Bacula data platforms, as well as many others. It can also monitor the backup execution process while tracking the storage and usage of backup servers.

NIS2 Requirement 4: Maintain supply chain security, including security-related aspects concerning the relationships between each entity and its direct suppliers or service providers.

Zabbix users can easily monitor third-party services and dependencies (such as APIs or libraries) for availability and performance, while being alerted to any potential vulnerabilities or disruptions in supply chain services. What’s more, Zabbix can also handle service monitoring and SLA reporting, keeping users updated around the clock on progress against predefined SLAs.

NIS2 Requirement 5: Provide security in network and information systems acquisition, development, and maintenance – including vulnerability handling and disclosure.

With Zabbix, a user can easily track software versions and check for outdated components, thanks to Zabbix’s ability to integrate with external tools for checking vulnerabilities.

NIS2 Requirement 6: Have policies and procedures in place regarding the use of cryptography and encryption.

Zabbix makes it simple for organizations of any size to comprehensively monitor encryption certificates for expiration.

NIS2 Requirement 7: Maintain HR security by providing accessible control and asset management policies.

Zabbix allows organizations to quickly and easily monitor user actions via log files.

NIS2 Requirement 8: Implement multi-factor authentication (MFA) or continuous authentication solutions, secured voice, video and text communications, and secured emergency communication systems.

Zabbix is set up to monitor the performance and uptime of any identity provider (IdP), using APIs provided by the IdPs themselves to query MFA policies and user login events. Zabbix can also monitor logs for MFA-related events while providing custom dashboards and reports on MFA usage.

In conclusion:

NIS2 is reshaping the cybersecurity landscape, and Zabbix has what it takes to equip organizations with the knowledge they need to thrive in this new regulatory environment. Trusting your monitoring to Zabbix can enhance your overall cybersecurity posture and supporting a comprehensive NIS2 implementation strategy.

To learn more, visit our website.

The post NIS2 Requirement Support: The Zabbix Advantage appeared first on Zabbix Blog.

Anthropic’s Claude 3.7 Sonnet hybrid reasoning model is now available in Amazon Bedrock

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/anthropics-claude-3-7-sonnet-the-first-hybrid-reasoning-model-is-now-available-in-amazon-bedrock/

Amazon Bedrock is expanding its foundation model (FM) offerings as the generative AI field evolves. Today, we’re excited to announce the availability of Anthropic’s Claude 3.7 Sonnet foundation model in Amazon Bedrock. As Anthropic’s most intelligent model to date, Claude 3.7 Sonnet stands out as their first hybrid reasoning model capable of producing quick responses or extended thinking, meaning it can work through difficult problems using careful, step-by-step reasoning. Additionally, today we are adding Claude 3.7 Sonnet to the list of models used by Amazon Q Developer. Amazon Q is built on Bedrock, and with Amazon Q you can use the most appropriate model for a specific task such as Claude 3.7 Sonnet, for more advanced coding workflows that enable developers to accelerate building across the entire software development lifecycle.

Key highlights of Claude 3.7 Sonnet
Here are several notable features and capabilities of Claude 3.7 Sonnet in Amazon Bedrock.

The first Claude model with hybrid reasoning – Claude 3.7 Sonnet takes a different approach to how models think. Instead of using separate models—one for quick answers and another for solving complex problems—Claude 3.7 Sonnet integrates reasoning as a core capability within a single model. This combination is more similar to how the human brains works. After all, we use the same brain whether we’re answering a simple question or solving a difficult puzzle.

The model has two modes—standard and extended thinking mode—which can be toggled in Amazon Bedrock. In standard mode, Claude 3.7 Sonnet is an improved version of Claude 3.5 Sonnet. In extended thinking mode, Claude 3.7 Sonnet takes additional time to analyze problems in detail, plan solutions, and consider multiple perspectives before providing a response, allowing it to make further gains in performance. You can control speed and cost by choosing when to use reasoning capabilities. Extended thinking tokens count towards the context window and are billed as output tokens.

Anthropic’s most powerful model for coding – Claude 3.7 Sonnet is state-of-the art for coding, excelling in understanding context and creative problem solving, and according to Anthropic, achieves an industry-leading 70.3% for standard mode on SWE-bench Verified. Claude 3.7 Sonnet also performs better than Claude 3.5 Sonnet across the majority of benchmarks. These enhanced capabilities make Claude 3.7 Sonnet ideal for powering AI agents and complex workflows.

Claude 3.7 Sonnet benchmarks

Source: https://www.anthropic.com/news/claude-3-7-sonnet

Over 15x longer output capacity than its predecessor – Compared to Claude 3.5 Sonnet, this model offers significantly expanded output length. This enhanced capacity is particularly useful when you explicitly request more detail, ask for multiple examples, or request additional context or background information. To achieve long outputs, try asking for a detailed outline (for writing use cases, you can specify outline detail down to the paragraph level and include word count targets). Then, ask for the response to index its paragraphs to the outline and reiterate the word counts. Claude 3.7 Sonnet supports outputs up to 128K tokens long (up to 64K as generally available and up to 128K as a beta).

Adjustable reasoning budget – You can control the budget for thinking when you use Claude 3.7 Sonnet in Amazon Bedrock. This flexibility helps you weigh the trade-offs between speed, cost, and performance. By allocating more tokens to reasoning for complex problems or limiting tokens for faster responses, you can optimize performance for your specific use case.

Claude 3.7 Sonnet in action
As for any new model, I have to request access in the Amazon Bedrock console. In the navigation pane, I choose Model access under Bedrock configurations. Then, I choose Modify model access to request access for Claude 3.7 Sonnet.

Model access in Amazon Bedrock

To try Claude 3.7 Sonnet, I choose Chat / Text under Playgrounds in the navigation pane. Then I choose Select model and choose Anthropic under the Categories and Claude 3.7 Sonnet under the Models. To enable the extended thinking mode, I toggle Model reasoning under Configurations. I type the following prompt, and choose Run:

You're the manager of a small restaurant facing these challenges:

Three staff members called in sick for tonight's dinner service
You're expecting a full house (80 seats)
There's a large party of 20 coming at 7 PM
Your main chef is available but two kitchen helpers are among those who called in sick
You have 2 regular servers and 1 trainee available
How would you:

Reorganize the available staff to handle the situation
Prioritize tasks and service
Determine if you need to make any adjustments to reservations
Handle the large party while maintaining service quality
Minimize negative impact on customer experience
Explain your reasoning for each decision and discuss potential trade-offs


Chat / Text playground

Here’s the result with an animated image showing the reasoning process of the model.

Testing Claude 3.7 Sonnet reasoning

To test image-to-text vision capabilities, I upload an image of a detailed architectural site plan created using Amazon Bedrock. I receive a detailed analysis and reasoned insights of this site plan.

Claude 3.7 Sonnet can also be accessed through AWS SDK by using Amazon Bedrock API. To learn more about Claude 3.7 Sonnet’s features and capabilities, visit the Anthropic’s Claude in Amazon Bedrock product detail page.

Get started with Claude 3.7 Sonnet today
Claude 3.7 Sonnet’s enhanced capabilities can benefit multiple industry use cases. Businesses can create advanced AI assistants and agents that interact directly with customers. In fields such as healthcare, it can assist in medical imaging analysis and research summarization, and financial services can benefit from its abilities to solve complex financial modeling problems. For developers, it serves as a coding companion that can review code, explain technical concepts, and suggest improvements across different languages.

Anthropic’s Claude 3.7 Sonnet is available today in the US East (N. Virginia), US East (Ohio), and US West (Oregon) Regions. Check the full Region list for future updates.

Claude 3.7 Sonnet is priced competitively and matches the price of Claude 3.5 Sonnet. For pricing details, refer to the Amazon Bedrock pricing page.

To get started with Claude 3.7 Sonnet in Amazon Bedrock, visit the Amazon Bedrock console and Amazon Bedrock documentation.

— Esra

AWS Weekly Roundup: Cloud Club Captain Applications, Formula 1®, Amazon Nova Prompt Engineering, and more (Feb 24, 2025)

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-cloud-club-captain-applications-formula-1-amazon-nova-prompt-engineering-and-more-feb-24-2025/

AWS Developer Day 2025, held on February 20th, showcased how to integrate responsible generative AI into development workflows. The event featured keynotes from AWS leaders including Srini Iragavarapu, Director Generative AI Applications and Developer Experiences, Jeff Barr, Vice President of AWS Evangelism, David Nalley, Director Open Source Marketing of AWS, along with AWS Heroes and technical community members. Watch the full event recording on Developer Day 2025.

Cloud Club

Applications are now open through March 6th for the 2025 AWS Cloud Clubs Captains program. AWS Cloud Clubs are student-led groups for post-secondary and independent students, 18 years old and over. Find a club near you on our Meetup page.

Last week’s launches
Here are some launches that got my attention:

Amplify Hosting announces support for IAM roles for server-side rendered (SSR) applications –  AWS Amplify Hosting now supports AWS Identity and Access Management (IAM) roles for SSR applications, enabling secure access to AWS services without managing credentials manually. Learn more in the IAM Compute Roles for Server-Side Rendering with AWS Amplify Hosting blog.

AWS WAF enhances Data Protection and logging experience –  AWS WAF expands its Data Protection capabilities allowing sensitive data in logs to be replaced with cryptographic hashes (e.g. ‘ade099751d2ea9f3393f0f’) or a predefined static string (‘REDACTED’) before logs are sent to WAF Sample Logs, Amazon Security Lake, Amazon CloudWatch, or other logging destinations.

Announcing AWS DMS Serverless comprehensive premigration assessments – AWS Database Migration Service Serverless (AWS DMS Serverless) now supports premigration assessments for replications to identify potential issues before database migrations begin. The tool analyzes source and target databases, providing recommendations for optimal DMS settings and best practices.

Amazon ECS increases the CPU limit for ECS tasks to 192 vCPUs – Amazon Elastic Container Service (Amazon ECS) now supports CPU limits of up to 192 vCPU for ECS tasks deployed on Amazon Elastic Compute Cloud (Amazon EC2) instances, an increase from the previous 10 vCPU limit. This enhancement allows customers to more effectively manage resource allocation on larger Amazon EC2 instances.

AWS Network Firewall introduces automated domain lists and insights – AWS Network Firewall now provides automated domain lists and insights by analyzing 30 days of HTTP/S traffic. This helps create and maintain allow-list policies more efficiently, at no extra cost.

AWS announces Backup Payment Methods for invoices – AWS now enables you to set up backup payment methods that automatically activate if primary payment fails. This helps prevent service interruptions and reduces manual intervention for invoice payments.

Get updated with all the announcements of AWS announcements on the What’s New with AWS? page.

Other AWS news
Here are additional noteworthy items:

AWS Partner Network: Essential training resources for ISV partners – To help scale solutions effectively, AWS provides essential training resources for Software Vendors (ISVs) partners in four key areas: AWS Marketplace fundamentals, Foundational Technical Review (FTR), APN Customer Engagement (ACE) program and co-selling, and Partner funding opportunities.

How Formula 1® uses generative AI to accelerate race-day issue resolution – Formula 1® (F1) uses Amazon Bedrock to speed up race-day issue resolution, reducing troubleshooting time from weeks to minutes through a chatbot that analyzes root causes and suggests fixes.

How Formula 1® uses generative AI to accelerate race-day issue resolution

Reducing hallucinations in LLM agents with a verified semantic cache using Amazon Bedrock Knowledge Bases – This blog introduces a solution using Amazon Bedrock Knowledge Bases and Amazon Bedrock Agents to reduce Large language models (LLMs) hallucinations by implementing a verified semantic cache that checks queries against curated answers before generating new responses, improving accuracy and response times.

Reducing hallucinations in LLM agents with a verified semantic cache using Amazon Bedrock Knowledge Bases

Orchestrate an intelligent document processing workflow using tools in Amazon Bedrock – This blog demonstrates an intelligent document processing workflow using Amazon Bedrock tools that combines Anthropic’s Claude 3 Haiku for orchestration and Anthropic’s Claude 3.5 Sonnet (v2) for analysis to handle structured, semi-structured, and unstructured healthcare documents efficiently.

From community.aws
Here are my personal favorites posts from community.aws:

Tracing Amazon Bedrock Agents – Learn how to track and analyze Amazon Bedrock Agents workflows using AWS X-Ray for better observability, by Randy D.

Testing Amazon ECS Network Resilience with AWS FIS – This article demonstrates how to test network resilience in Amazon ECS using AWS FIS with guidance from Amazon Q Developer, by Sunil Govindankutty

Stop Using Default Arguments in AWS Lambda Functions – Discover why your AWS Lambda costs might be spiralling out of control due to a common Python programming practice, by Stuart Clark.

Amazon Nova Prompt Engineering on AWS: A Field Guide by Brooke – A field guide for using Amazon Nova models, covering prompt engineering patterns and best practices on AWS, by Brooke Jamieson.

Amazon Nova Prompt Engineering on AWS: A Field Guide by Brooke

Creating Deployment Configurations for EKS with Amazon Q – Amazon Q Developer helps create EKS deployments by providing templates and best practices for Kubernetes configs, by Ricardo Tasso.

Processing WhatsApp Multimedia with Amazon Bedrock Agents: Images, Video, and Documents – I invite you to read my latest blog, which explains how to create a WhatsApp AI assistant using Amazon Bedrock and Amazon Nova models to process multimedia content such as images, videos, documents, and audio.

Processing WhatsApp Multimedia with Amazon Bedrock Agents: Images, Video, and Documents

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS GenAI Lofts – GenAI Lofts offer collaborative spaces and immersive experiences for startups and developers. You can join in-person GenAI Loft San Francisco events such as Hands-on with Agentic Graph RAG Workshop (February 25), Unstructured Data Meetup SF (February 26 – 27) and AI Tinkerers – San Francisco – February 2025 Demos + Science Fair (February 27 – 28). GenAI Loft Berlin has events and workshops on February 24 to March 7 that you can’t miss!

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czeh Republic (April 29).

AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations. Available in multiple geographic regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS re:Inforce – AWS re:Inforce (June 16–18) in Philadelphia, PA our annual learning event devoted to all things AWS cloud security. Registration opens in March, and be ready to join more than 5,000 security builders and leaders.

Create your AWS Builder ID and reserve your alias. Builder ID is a universal login credential that gives you access–beyond the AWS Management Console–to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Stay tuned for next week’s Weekly Roundup!

— Eli

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS Weekly Roundup: AWS Developer Day, Trust Center, Well-Architected for Enterprises, and more (Feb 17, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-developer-day-trust-center-well-architected-for-enterprises-and-more-feb-17-2025/

Join us for the AWS Developer Day on February 20! This virtual event is designed to help developers and teams incorporate cutting-edge yet responsible generative AI across their development lifecycle to accelerate innovation.

In his keynote, Jeff Barr, Vice President of AWS Evangelism, shares his thoughts on the next generation of software development based on generative AI, the skills needed to thrive in this changing environment, and how he sees it evolving in the future.

Get a first look at exciting technical deep-dive and product updates about Amazon Q Developer, AWS Amplify, and GitLab Duo with Amazon Q. You get the chance to explore real-world use cases, live coding demos, interactive sessions, and community spotlight sessions with Christian Bonzelet (AWS Community Builder), Hazel Saenz (AWS Serverless Hero), Matt Lewis (AWS Data Hero), and Johannes Koch (AWS DevTools Hero). Please sign up for this event now!

Last week’s launches
Here are some launches that got my attention:

Updating AWS SDK defaults for AWS STS – As we shared upcoming changes to the AWS Security Token Service (AWS STS) global endpoint to improve the resiliency and performance of your applications, we’re updating two defaults of AWS Software Development Kits (AWS SDKs) and AWS Command Line Interfaces (AWS CLIs) on July 31st 2025 – the default AWS STS service to regional, and the default retry strategy to standard. We recommend that you test your application before the release to avoid an unexpected experience after updating.

Introducing the AWS Trust Center – Chris Betz, CISO at Amazon Web Services (AWS), shared AWS Trust Center, a new online resource communicating how we approach securing your assets in the cloud. This resource is a window into our security practices, compliance programs, and data protection controls that demonstrates how we work to earn your trust every day.

AWS CloudTrail network activity events for VPC endpoint – This feature provides you with a powerful tool to enhance your security posture, detect potential threats, and gain deeper insights into your VPC network traffic. This feature addresses your critical needs for comprehensive visibility and control over your AWS environments.

AWS Verified Access support for non-HTTP resources – AWS Verified Access now extends beyond HTTP apps to provide VPN-less, secure access to non-HTTP resources like Amazon Relational Database Service (Amazon RDS) databases, enabling improved security and enhanced user experience for both web applications and database connections. To learn more, visit the Verified Access endpoints page and a video tutorial.

New subnet management of Network Load Balancer (NLB) – NLBs were previously restricted to only adding subnets in new Availability Zones, and they now support full subnet management, including removal of subnets, matching the capabilities of Application Load Balancer (ALB). This enhancement offers organizations greater control over their network architecture and brings consistency to AWS load balancing services.

Meta SAM 2.1 and Falcon 3 models in Amazon SageMaker JumpStart – You can use Meta’s Segment Anything Model (SAM) 2.1 with state-of-the-art video and image segmentation capabilities in a single model. You can also use the Falcon 3 family with five models ranging from 1 to 10 billion parameters, with a focus on enhancing science, math, and coding capabilities. To learn more, visit SageMaker JumpStart pretrained models and Getting started with Amazon SageMaker JumpStart.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Here are some additional news items that you might find interesting:

AWS Documentation update – Greg Wilson, a lead of AWS Documentation, SDK, and CLI teams shared an insightful blog post about the progress, challenges, and what’s next for technical documentation for 200+ AWS services. It includes AWS Decision Guides for choosing the right service for specific needs; optimizing documents for readability, such as doubled code samples; and improving usability, such as dark mode and auto-suggest with top global navigation controls. You can also learn about how we use generative AI to help create technical documents.

AWS Well-Architected for Enterprises – This is a new free digital course designed for technical professionals who architect, build, and operate AWS solutions at scale. This intermediate-level course will help you optimize your cloud architecture while aligning to your business goals. The course takes approximately 1 hour to complete and includes a knowledge check at the end to reinforce your learning.

Integrating AWS with .NET Aspire – The .NET team at AWS has been working on integrations for connecting your .NET applications to AWS resources. Learn about how to automatically deploy AWS application resources using Aspire.Hosting.AWS NuGet package for NET Aspire, an open source framework building cloud-ready applications.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

AWS Innovate: Generative AI + Data – Join a free online conference focusing on generative AI and data innovations. Available in multiple geographic regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Paris (April 9), Amsterdam (April 16), London (April 30), and Poland (May 5).

AWS GenAI Lofts – GenAI Lofts offer collaborative spaces and immersive experiences for startups and developers. You can join in-person GenAI Loft San Francisco events such as Built on Amazon Bedrock demo nights (April 19), SageMaker Unified Studio Demo for Startups (April 21), and Hands-on with Agentic Graph RAG Workshop (April 25). GenAI Loft Berlin has its Opening Day on February 24 and goes to March 7.

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Karachi, Pakistan (February 22), Milan, Italy (April 2), Bay Area – Security Edition (April 4), Timișoara, Romania (April 10), and Prague, Czeh Republic (April 29).

AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity. You can subscribe for event updates now!

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS CloudTrail network activity events for VPC endpoints now generally available

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-cloudtrail-network-activity-events-for-vpc-endpoints-now-generally-available/

Today, I’m happy to announce the general availability of network activity events for Amazon Virtual Private Cloud (Amazon VPC) endpoints in AWS CloudTrail. This feature helps you to record and monitor AWS API activity traversing your VPC endpoints, helping you strengthen your data perimeter and implement better detective controls.

Previously, it was hard to detect potential data exfiltration attempts and unauthorized access to the resources within your network through VPC endpoints. While VPC endpoint policies could be configured to prevent access from external accounts, there was no built-in mechanism to log denied actions or detect when external credentials were used at a VPC endpoint. This often required you to build custom solutions to inspect and analyze TLS traffic, which could be operationally costly and negate the benefits of encrypted communications.

With this new capability, you can now opt in to log all AWS API activity passing through your VPC endpoints. CloudTrail records these events as a new event type called network activity events, which capture both control plane and data plane actions passing through a VPC endpoint.

Network activity events in CloudTrail provide several key benefits:

  • Comprehensive visibility – Log all API activity traversing VPC endpoints, regardless of the AWS account initiating the action.
  • External credential detection – Identify when credentials from outside your organization are accessing your VPC endpoint.
  • Data exfiltration prevention – Detect and investigate potential unauthorized data movement attempts.
  • Enhanced security monitoring – Gain insights into all AWS API activity at your VPC endpoints without the need to decrypt TLS traffic.
  • Visibility for regulatory compliance – Improve your ability to meet regulatory requirements by tracking all API activity passing through.

Getting started with network activity events for VPC endpoint logging
To enable network activity events, I go to the AWS CloudTrail console and choose Trails in the navigation pane. I choose Create trail to create a new one. I enter a name in the Trail name field and choose an Amazon Simple Storage Service (Amazon S3) bucket to store the event logs. When I create a trail in CloudTrail, I can specify an existing Amazon S3 bucket or create a new bucket to store my trail’s event logs.

If you set Log file SSE-KMS encryption to Enabled, you have two options: Choose New to create a new AWS Key Management Service (AWS KMS) key or choose Existing to choose an existing KMS key. If you chose New, you need to type an alias in the AWS KMS alias field. CloudTrail encrypts your log files with this KMS key and adds the policy for you. The KMS key and Amazon S3 must be in the same AWS Region. For this example, I use an existing KMS key. I enter the alias in the AWS KMS alias field and leave the rest as default for this demo. I choose Next for the next step.

In the Choose log events step, I choose Network activity events under Events. I choose the event source from the list of AWS services, such as cloudtrail.amazonaws.com, ec2.amazonaws.com, kms.amazonaws.com, s3.amazonaws.com, and secretsmanager.amazonaws.com. I add two network activity event sources for this demo. For the first source, I select ec2.amazonaws.com option. For Log selector template, I can use templates for common use cases or create fine-grained filters for specific scenarios. For example, to log all API activities traversing the VPC endpoint, I can choose the Log all events template. I choose Log network activity access denied events template to log only access denied events. Optionally, I can enter a name in the Selector name field to identify the log selector template, such as Include network activity events for Amazon EC2.

As a second example, I choose Custom to create custom filters on multiple fields, such as eventName and vpcEndpointId. I can specify specific VPC endpoint IDs or filter the results to include only the VPC endpoints that match specific criteria. For Advanced event selectors, I choose vpcEndpointId from the Field dropdown, choose equals as Operator, and enter the VPC endpoint ID. When I expand the JSON view, I can see my event selectors as a JSON block. I choose Next and after reviewing the selections, I choose Create trail.

After it’s configured, CloudTrail will begin logging network activity events for my VPC endpoints, helping me analyze and act on this data. To analyze AWS CloudTrail network activity events, you can use the CloudTrail console, AWS Command Line Interface (AWS CLI), and AWS SDK to retrieve relevant logs. You can also use CloudTrail Lake to capture, store and analyze your network activity events. If you are using Trails, you can use Amazon Athena to query and filter these events based on specific criteria. Regular analysis of these events can help you maintain security, comply with regulations, and optimize your network infrastructure in AWS.

Now available
CloudTrail network activity events for VPC endpoint logging provide you with a powerful tool to enhance your security posture, detect potential threats, and gain deeper insights into your VPC network traffic. This feature addresses your critical needs for comprehensive visibility and control over your AWS environments.

Network activity events for VPC endpoints are available in all commercial AWS Regions.

For pricing information, visit AWS CloudTrail pricing.

To get started with CloudTrail network activity events, visit AWS CloudTrail. For more information on CloudTrail and its features, refer to the AWS CloudTrail documentation.

— Esra

AWS Weekly Roundup: AWS Step Functions, AWS CloudFormation, Amazon Q Developer, and more (February 10, 2024)

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-step-functions-aws-cloudformation-amazon-q-developer-and-more-february-10-2024/

We are well settled into 2025 by now, but many people are still catching up with all the exciting new releases and announcements that came out of re:Invent last year. There have been hundreds of re:Invent recap events around the world since the beginning of the year, including in-person all-day official AWS events with multiple tracks to help you discover and dive deeper into the releases you care about, as well as community and virtual events.

Last month, I was lucky to be a co-host for AWS EMEA re:Invent re:Cap which was a nearly 4-hour livestream with experts featuring demos, whiteboard sessions, and a live Q&A. The good news is that you can now watch it on-demand! We had a great team and thousands of people enjoyed learning through the virtual experience. I recommend you check it out or share it with colleagues who have not been able to attend any re:Invent re:Cap events.

The Korean team also did an amazing job hosting their own virtual re:Invent re:Cap event, and it’s also now available on-demand. So if you speak Korean I do recommend you check it out.

If you’re more of a reader, then we have a treat for you. You can download the full official re:Invent re:Cap deck with all the slides covering releases across all areas by visiting community.aws! While there, you can also check all the upcoming in-person re:Invent re:Cap community events remaining across the globe for a chance to still attend one of those in a city near you.

But as we know, new releases, announcements, and updates don’t stop at re:Invent. Every week there are even more, and this is why we have this Weekly Roundup series that you can read every Monday to get the AWS news highlights from the week before.

So here’s what caught my attention last week.

Last week’s AWS Launches
If you use AWS Step Functions you may be interested in these:

Amazon Q Developer also got a couple of updates:

Here are some other releases that caught my attention this week from a variety of other AWS services:

AWS CloudFormation introduces stack refactoring – You can now split your CloudFormation stacks, move resources from one stack to another, and change the logical name of resources within the same stack. This adds a lot of flexibility enabling you to keep up with changes within your organization and architectures, such as streamlining resource lifecycle management for existing stacks, keeping up with naming convention changes, and other cases. You can refactor your stacks by using the AWS command line interface (CLI) or AWS SDK.

AWS Config now supports 4 new release types – AWS Config is great for monitoring resources across your AWS environment and help you towards ensuring alignment with your company and security policies as well as compliance requirements. It now has four new types of resources enabling you to monitor Amazon VPC block public access settings, any exceptions made within those settings, as well as monitor S3 Express One Zone bucket policies and directory bucket settings.

Automated recovery of Microsoft SQL Server on EC2 instan ces with VSS – You can now use a new feature called Volume Shadow Copy Services (VSS) to backup Microsoft SQL Server databases to Amazon Elastic Block Store (EBS) snapshots while the database is running. You can then use AWS Systems Manager Automation Runbook to set a recovery point of time of your preference and it will restore the database automatically from your VSS-based EBS snapshot without incurring any downtime.

Other updates
Upcoming changes to the AWS Security Token Service (AWS STS) global endpoint – To help improve the resiliency and performance of your applications, we are making changes to the AWS STS global endpoint (https://sts.amazonaws.com), with no action required from customers. Starting in early 2025, requests to the STS global endpoint will be automatically served in the same Region as your AWS deployed workloads. For example, if your application calls sts.amazonaws.com from the US West (Oregon) Region, your calls will be served locally in the US West (Oregon) Region instead of being served by the US East (N. Virginia) Region. These changes will be released in the coming weeks and we will gradually roll it out to AWS Regions that are enabled by default by mid-2025.

Upcoming AWS and community events

AWS Public Sector Day London, February 27 — Join public sector leaders and innovators to explore how AWS is enabling digital transformation in government, education, and healthcare.

AWS Innovate GenAI + Data Edition — A free online conference focusing on generative AI and data innovations. Available in multiple Regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

Browse more upcoming AWS led in-person and virtual developer-focused events.

Looking for some reading recommendations? At the beginning of every year Dr. Werner Vogles, VP and CTO of Amazon, publishes a list of recommended books that he believes should have your attention. This year’s list is looking particularly good in my opinion!

That’s it for this week! For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

See you next time 🙂

Matheus Guimaraes | @codingmatheus

AWS CodeBuild for macOS adds support for Fastlane

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/codebuild-for-macos-adds-support-for-fastlane/

I’m pleased to announce the availability of Fastlane in your AWS CodeBuild for macOS environments. AWS CodeBuild is a fully managed continuous integration service that compiles source code, runs tests, and produces ready-to-deploy software packages.

Fastlane is an open source tool suite designed to automate various aspects of mobile application development. It provides mobile application developers with a centralized set of tools to manage tasks such as code signing, screenshot generation, beta distribution, and app store submissions. It integrates with popular continuous integration and continuous deployment (CI/CD) platforms and supports both iOS and Android development workflows. Although Fastlane offers significant automation capabilities, developers may encounter challenges during its setup and maintenance. Configuring Fastlane can be complex, particularly for teams unfamiliar with the syntax and package management system of Ruby. Keeping Fastlane and its dependencies up to date requires ongoing effort, because updates to mobile platforms or third-party services may necessitate adjustments to existing workflows.

When we introduced CodeBuild for macOS in August 2024, we knew that one of your challenges was to install and maintain Fastlane in your build environment. Although it was possible to manually install Fastlane in a custom build environment, at AWS, we remove the undifferentiated heaving lifting from your infrastructure so you can spend more time on the aspects that matter for your business. Starting today, Fastlane is installed by default, and you can use the familiar command fastlane buildin your buildspec.yaml file.

Fastlane and code signing
To distribute an application on the App Store, developers must sign their binary with a private key generated on the Apple Developer portal. This private key, along with the certificate that validates it, must be accessible during the build process. This can be a challenge for development teams because they need to share the development private key (which allows deployment on selected test devices) among team members. Additionally, the distribution private key (which enables publishing on the App Store) must be available during the signing process before uploading the binary to the App Store.

Fastlane is a versatile build system in that it also helps developers with the management of development and distribution keys and certificates. Developers can use fastlane match to share signing materials in a team and make them securely and easily accessible on individual developers’ machines and on the CI environment. match allows the storage of private keys, the certificates, and the mobile provisioning profiles on a secured share storage. It makes sure that the local build environment, whether it’s a developer laptop or a server machine in the cloud, stays in sync with the shared storage. At build time, it securely downloads the required certificates to sign your app and configures the build machine to allow the codesign utility to pick them up.

match allows the sharing of signing secrets through GitHub, GitLab, Google Cloud Storage, Azure DevOps, and Amazon Simple Storage Service (Amazon S3).

If you already use one of these and you’re migrating your projects to CodeBuild, you don’t have much to do. You only need to make sure your CodeBuild build environment has access to the shared storage (see step 3 in the demo).

Let’s see how it works
If you’re new to Fastlane or CodeBuild, let’s see how it works.

For this demo, I start with an existing iOS project. The project is already configured to be built on CodeBuild. You can refer to my previous blog post, Add macOS to your continuous integration pipelines with AWS CodeBuild, to learn more details.

I’ll show you how to get started in three steps:

  • Import your existing signing materials to a shared private GitHub repository
  • Configure fastlane to build and sign your project
  • Use fastlanewith CodeBuild

Step 1: Import your signing materials

Most of the fastlane documentation I read explains how to create a new key pair and a new certificate to get started. Although this is certainly true for new projects, in real life, you probably already have your project and your signing keys. So, the first step is to import these existing signing materials.

Apple App Store uses different keys and certificates for development and distribution (there are also ad hoc and enterprise certificates, but these are outside the scope of this post). You must have three files for each usage (that’s a total of six files):

  • A .mobileprovision file that you can create and download from the Apple developer console. The provisioning profile links your identity, the app identity, and the entitlements the app might have.
  • A .cer file, which is the certificate emitted by Apple to validate your private key. You can download this from the Apple Developer portal. Select the certificate, then select Download.
  • A .p12 file, which contains your private key. You can download the key when you create it in the Apple Developer portal. If you didn’t download it but have it on your machine, you can export it from the Apple Keychain app. Note that the KeyChain.app is hidden in macOS 15.x. You can open it with open /System/Library/CoreServices/Applications/Keychain\ Access.app. Select the key you want to export and right click to select Export.
Export p12 files from Keychain

When you have these files, create a fastlane/Matchfile file with the following content:

git_url("https://github.com/sebsto/secret.git")
storage_mode("git")
type("development")
# or use appstore to use the distribution signing key and certificate
# type("appstore")

Be sure to replace the URL of your GitHub repository and make sure this repository is private. It will serve as a storage for your signing key and certificate.

Then, I import my existing files with the fastlane match import --type appstore command. I repeat the command for each environment: appstore and development.

The very first time, fastlane prompts me for my Apple Id username and password. It connects to App Store Connect to verify the validity of the certificates or to create new ones when necessary. The session cookie is stored in ~/.fastlane/spaceship/<your apple user id>/cookie.

fastlane match also asks for a password. It uses this password to generate a key to crypt the signing materials on the storage. Don’t forget this password because it will be used at build time to import the signing materials on the build machine.

Here is the command and its output in full:

 fastlane match import --type appstore

[✔] 🚀
[16:43:54]: Successfully loaded '~/amplify-ios-getting-started/code/fastlane/Matchfile' 📄

+-----------------------------------------------------+
| Detected Values from './fastlane/Matchfile'         |
+--------------+--------------------------------------+
| git_url.     | https://github.com/sebsto/secret.git |
| storage_mode | git                                  |
| type         | development                          |
+--------------+--------------------------------------+

[16:43:54]: Certificate (.cer) path:
./secrets/sebsto-apple-dist.cer
[16:44:07]: Private key (.p12) path:
./secrets/sebsto-apple-dist.p12
[16:44:12]: Provisioning profile (.mobileprovision or .provisionprofile) path or leave empty to skip
this file:
./secrets/amplifyiosgettingstarteddist.mobileprovision
[16:44:25]: Cloning remote git repo...
[16:44:25]: If cloning the repo takes too long, you can use the `clone_branch_directly` option in match.
[16:44:27]: Checking out branch master...
[16:44:27]: Enter the passphrase that should be used to encrypt/decrypt your certificates
[16:44:27]: This passphrase is specific per repository and will be stored in your local keychain
[16:44:27]: Make sure to remember the password, as you'll need it when you run match on a different machine
[16:44:27]: Passphrase for Match storage: ********
[16:44:30]: Type passphrase again: ********
security: SecKeychainAddInternetPassword <NULL>: The specified item already exists in the keychain.
[16:44:31]: 🔓 Successfully decrypted certificates repo
[16:44:31]: Repo is at: '/var/folders/14/nwpsn4b504gfp02_mrbyd2jr0000gr/T/d20250131-41830-z7b4ic'
[16:44:31]: Login to App Store Connect ([email protected])
[16:44:33]: Enter the passphrase that should be used to encrypt/decrypt your certificates
[16:44:33]: This passphrase is specific per repository and will be stored in your local keychain
[16:44:33]: Make sure to remember the password, as you'll need it when you run match on a different machine
[16:44:33]: Passphrase for Match storage: ********
[16:44:37]: Type passphrase again: ********
security: SecKeychainAddInternetPassword <NULL>: The specified item already exists in the keychain.
[16:44:39]: 🔒 Successfully encrypted certificates repo
[16:44:39]: Pushing changes to remote git repo...
[16:44:40]: Finished uploading files to Git Repo [https://github.com/sebsto/secret.git]

I verify that Fastlane imported my signing material to my Git repository.

Fastlane match - github repo after import

I can also configure my local machine to use these signing materials during the next build:

» fastlane match appstore 

[✔] 🚀 
[17:39:08]: Successfully loaded '~/amplify-ios-getting-started/code/fastlane/Matchfile' 📄

+-----------------------------------------------------+
|   Detected Values from './fastlane/Matchfile'       |
+--------------+--------------------------------------+
| git_url      | https://github.com/sebsto/secret.git |
| storage_mode | git                                  |
| type         | development                          |
+--------------+--------------------------------------+


+-------------------------------------------------------------------------------------------+
|                                 Summary for match 2.226.0                                 |
+----------------------------------------+--------------------------------------------------+
| type                                   | appstore                                         |
| readonly                               | false                                            |
| generate_apple_certs                   | true                                             |
| skip_provisioning_profiles             | false                                            |
| app_identifier                         | ["com.amazonaws.amplify.mobile.getting-started"] |
| username                               | xxxx@xxxxxxxxx                                   |
| team_id                                | XXXXXXXXXX                                       |
| storage_mode                           | git                                              |
| git_url                                | https://github.com/sebsto/secret.git             |
| git_branch                             | master                                           |
| shallow_clone                          | false                                            |
| clone_branch_directly                  | false                                            |
| skip_google_cloud_account_confirmation | false                                            |
| s3_skip_encryption                     | false                                            |
| gitlab_host                            | https://gitlab.com                               |
| keychain_name                          | login.keychain                                   |
| force                                  | false                                            |
| force_for_new_devices                  | false                                            |
| include_mac_in_profiles                | false                                            |
| include_all_certificates               | false                                            |
| force_for_new_certificates             | false                                            |
| skip_confirmation                      | false                                            |
| safe_remove_certs                      | false                                            |
| skip_docs                              | false                                            |
| platform                               | ios                                              |
| derive_catalyst_app_identifier         | false                                            |
| fail_on_name_taken                     | false                                            |
| skip_certificate_matching              | false                                            |
| skip_set_partition_list                | false                                            |
| force_legacy_encryption                | false                                            |
| verbose                                | false                                            |
+----------------------------------------+--------------------------------------------------+

[17:39:08]: Cloning remote git repo...
[17:39:08]: If cloning the repo takes too long, you can use the `clone_branch_directly` option in match.
[17:39:10]: Checking out branch master...
[17:39:10]: Enter the passphrase that should be used to encrypt/decrypt your certificates
[17:39:10]: This passphrase is specific per repository and will be stored in your local keychain
[17:39:10]: Make sure to remember the password, as you'll need it when you run match on a different machine
[17:39:10]: Passphrase for Match storage: ********
[17:39:13]: Type passphrase again: ********
security: SecKeychainAddInternetPassword <NULL>: The specified item already exists in the keychain.
[17:39:15]: 🔓  Successfully decrypted certificates repo
[17:39:15]: Verifying that the certificate and profile are still valid on the Dev Portal...
[17:39:17]: Installing certificate...

+-------------------------------------------------------------------------+
|                          Installed Certificate                          |
+-------------------+-----------------------------------------------------+
| User ID           | XXXXXXXXXX                                          |
| Common Name       | Apple Distribution: Sebastien Stormacq (XXXXXXXXXX) |
| Organisation Unit | XXXXXXXXXX                                          |
| Organisation      | Sebastien Stormacq                                  |
| Country           | US                                                  |
| Start Datetime    | 2024-10-29 09:55:43 UTC                             |
| End Datetime      | 2025-10-29 09:55:42 UTC                             |
+-------------------+-----------------------------------------------------+

[17:39:18]: Installing provisioning profile...

+-------------------------------------------------------------------------------------------------------------------+
|                                          Installed Provisioning Profile                                           |
+---------------------+----------------------------------------------+----------------------------------------------+
| Parameter           | Environment Variable                         | Value                                        |
+---------------------+----------------------------------------------+----------------------------------------------+
| App Identifier      |                                              | com.amazonaws.amplify.mobile.getting-starte  |
|                     |                                              | d                                            |
| Type                |                                              | appstore                                     |
| Platform            |                                              | ios                                          |
| Profile UUID        | sigh_com.amazonaws.amplify.mobile.getting-s  | 4e497882-d80f-4684-945a-8bfec1b310b9         |
|                     | tarted_appstore                              |                                              |
| Profile Name        | sigh_com.amazonaws.amplify.mobile.getting-s  | amplify-ios-getting-started-dist             |
|                     | tarted_appstore_profile-name                 |                                              |
| Profile Path        | sigh_com.amazonaws.amplify.mobile.getting-s  | /Users/stormacq/Library/MobileDevice/Provis  |
|                     | tarted_appstore_profile-path                 | ioning                                       |
|                     |                                              | Profiles/4e497882-d80f-4684-945a-8bfec1b310  |
|                     |                                              | b9.mobileprovision                           |
| Development Team ID | sigh_com.amazonaws.amplify.mobile.getting-s  | XXXXXXXXXX                                   |
|                     | tarted_appstore_team-id                      |                                              |
| Certificate Name    | sigh_com.amazonaws.amplify.mobile.getting-s  | Apple Distribution: Sebastien Stormacq       |
|                     | tarted_appstore_certificate-name             | (XXXXXXXXXX)                                 |
+---------------------+----------------------------------------------+----------------------------------------------+

[17:39:18]: All required keys, certificates and provisioning profiles are installed 🙌

Step 2: Configure Fastlane to sign your project

I create a Fastlane build configuration file in fastlane/Fastfile (you can use fastlane init command to get started):

default_platform(:ios)

platform :ios do
  before_all do
    setup_ci
  end

  desc "Build and Sign the binary"
  lane :build do
    match(type: "appstore", readonly: true)
    gym(
      scheme: "getting started",
      export_method: "app-store"
    )
  end
end

Make sure that the setup_ci action is added to the before_all section of Fastfile for the match action to function correctly. This action creates a temporary Fastlane keychain with correct permissions. Without this step, you may encounter build failures or inconsistent results.

And I test a local build with the command fastlane build. I enter the password I used when importing my keys and certificate, then I let the system build and sign my project. When everything is correctly configured, it produces a similar output.

...
[17:58:33]: Successfully exported and compressed dSYM file
[17:58:33]: Successfully exported and signed the ipa file:
[17:58:33]: ~/amplify-ios-getting-started/code/getting started.ipa

+---------------------------------------+
|           fastlane summary            |
+------+------------------+-------------+
| Step | Action           | Time (in s) |
+------+------------------+-------------+
| 1    | default_platform | 0           |
| 2    | setup_ci         | 0           |
| 3    | match            | 36          |
| 4    | gym              | 151         |
+------+------------------+-------------+

[17:58:33]: fastlane.tools finished successfully 🎉

Step 3: Configure CodeBuild to use Fastlane

Next, I create a project on CodeBuild. I’m not going into the step-by-step guide to help you to do so. You can refer to my previous post or to the CodeBuild documentation.

There is just one Fastlane-specific configuration. To access the signing materials, Fastlane requires access to three secret values that I’ll pass as environment variables:

  • MATCH_PASSWORD, the password I entered when importing the signing material. Fastlane uses this password to decipher the encrypted files in the GitHub repository
  • FASTLANE_SESSION, the value of the Apple Id session cookie, located at ~/.fastlane/spaceship/<your apple user id>/cookie. The session is valid from a couple of hours to multiple days. When the session expires, reauthenticate with the command fastlane spaceauth from your laptop and update the value of FASTLANE_SESSION with the new value of the cookie.
  • MATCH_GIT_BASIC_AUTHORIZATION, a base 64 encoding of your GitHub username, followed by a colon, followed by a personal authentication token (PAT) to access your private GitHub repository. You can generate PAT on the GitHub console in Your Profile > Settings > Developers Settings > Personal Access Token. I use this command to generate the value of this environment variable: echo -n my_git_username:my_git_pat | base64.

Note that for each of these three values, I can enter the Amazon Resource Name (ARN) of the secret on AWS Secrets Manager or the plain text value. We strongly recommend using Secrets Manager to store security-sensitive values.

I’m a security-conscious user, so I store the three secrets in Secrets Manager with these commands:

aws --region $REGION secretsmanager create-secret --name /CodeBuild/MATCH_PASSWORD --secret-string MySuperSecretPassword
aws --region $REGION secretsmanager create-secret --name /CodeBuild/FASTLANE_SESSION --secret-string $(cat ~/.fastlane/spaceship/my_appleid_username/cookie)
aws --region $REGION secretsmanager create-secret --name /CodeBuild/MATCH_GIT_BASIC_AUTHORIZATION --secret-string $(echo -n my_git_username:my_git_pat | base64)

If your build project refers to secrets stored in Secrets Manager, the build project’s service role must allow the secretsmanager:GetSecretValue action. If you chose New service role when you created your project, CodeBuild includes this action in the default service role for your build project. However, if you chose Existing service role, you must include this action to your service role separately.

For this demo, I use this AWS Identity and Access Management (IAM) policy:

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Effect": "Allow",
			"Action": [
				"secretsmanager:GetSecretValue"
			],
			"Resource": [
				"arn:aws:secretsmanager:us-east-2:012345678912:secret:/CodeBuild/*"
			]
		}
	]
}

After I created the project in the CodeBuild section of the AWS Management Console, I enter the three environment variables. Notice that the value is the name of the secret in Secrets Manager.

Codebuild - environment variables for Fastlane match

You can also define the environment variables and their Secrets Manager secret name in your buildpsec.yaml file.

Next, I modify the buildspec.yaml file at the root of my project to use fastlane to build and sign the binary. My buildspec.yaml file now looks like this one:

# buildspec.yml
version: 0.2
phases:
  install:
    commands:
      - code/ci_actions/00_install_rosetta.sh
  pre_build:
    commands:
      - code/ci_actions/02_amplify.sh
  build:
    commands:
      - (cd code && fastlane build)
artifacts:
  name: getting-started-$(date +%Y-%m-%d).ipa
  files:
    - 'getting started.ipa'
  base-directory: 'code'

The Rosetta and Amplify scripts are required to receive the Amplify configuration for the backend. If you don’t use AWS Amplify in your project, you don’t need these.

Notice that there is nothing in the build file that downloads the signing key or prepares the keychain in the build environment; fastlane match will do that for me.

I add the new buildspec.yaml file and my ./fastlane directory to Git. I commit and push these files. git commit -m "add fastlane support" && git push

When everything goes well, I can see the build running on CodeBuild and the Succeeded message.

Codebuild - succeed message

Pricing and availability
Fastlane is now pre-installed at no extra cost on all macOS images that CodeBuild uses, in all Regions where CodeBuild for macOS is available. At the time of this writing, these are US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Sydney), and Europe (Frankfurt).

In my experience, it takes a bit of time to configure fastlane match correctly. When it’s configured, having it working on CodeBuild is pretty straightforward. Before trying this on CodeBuild, be sure it works on your local machine. When something goes wrong on CodeBuild, triple-check the values of the environment variables and make sure CodeBuild has access to your secrets on AWS Secrets Manager.

Now go build (on macOS)!

AWS Weekly Roundup: DeepSeek-R1, S3 Metadata, Elastic Beanstalk updates, and more (February 3, 2024)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-deepseek-r1-s3-metadata-elastic-beanstalk-updates-and-more-february-3-2024/

Last week, I had an amazing time attending AWS Community Day Thailand in Bangkok. This event came at an exciting time, following the recent launch of the AWS Asia Pacific (Bangkok) Region. We had over 300 attendees and featured 15 speakers from the community, including an AWS Hero and 4 AWS Community Builders who shared their technical expertise and experiences.

The highlight was definitely Jeff Barr, AWS Vice President & Chief Evangelist, delivering an inspiring keynote titled “Next-Generation Software Development”, which set the perfect tone for the day. The day kicked off with welcoming remarks from Vatsun Thirapatarapong, AWS Country Manager for Thailand, and was made even more special thanks to the tremendous support from both the AWS User Group volunteers and the AWS Thailand team.

Here’s a photo capturing the excitement from the event: 

Last week’s AWS Launches
There are 30+ launches last week and here are some launches that caught my attention:

DeepSeek-R1 models now available on AWS — Channy wrote on how you can now deploy DeepSeek-R1 models in Amazon Bedrock and Amazon SageMaker AI. This helps you to build and scale generative AI applications with minimal infrastructure investment.

Amazon S3 Tables increases table limit to 10,000 per bucket — S3 Tables now supports creating up to 10,000 tables in each table bucket, allowing you to scale up to 100,000 tables across 10 buckets within an AWS Region per account.

Amazon S3 Metadata now generally available — S3 Metadata provides automated and easily queried metadata that updates in near real-time, simplifying business analytics and real-time inference applications. It supports both system-defined and custom metadata, including integration with AWS analytics services.

AWS Amplify adds TypeScript Data client support for Lambda functions — Developers can now use the Amplify Data client within AWS Lambda functions, enabling consistent type-safe data operations across frontend and backend applications.

AWS Elastic Beanstalk adds Python 3.13, .NET 9, and PHP 8.4 support on Amazon Linux 2023 — AWS Elastic Beanstalk brings the latest language features and improvements to application deployments while benefiting from Amazon Linux 2023 enhanced security and performance features.

From community.aws
Here’s my top 5 personal favorites posts from community.aws:

Upcoming AWS and community events
Check your calendars and sign up for upcoming AWS and community events:

  • AWS Korea re:Invent reCap Online, February 2-4 — A virtual event recapping key announcements and innovations from re:Invent 2023 for the Korean audience.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs. Upcoming AWS Community Day is in Ahmedabad (February 8).
  • AWS Public Sector Day London, February 27 — Join public sector leaders and innovators to explore how AWS is enabling digital transformation in government, education, and healthcare.
  • AWS Innovate GenAI + Data Edition — A free online conference focusing on generative AI and data innovations. Available in multiple Regions: APJC and EMEA (March 6), North America (March 13), Greater China Region (March 14), and Latin America (April 8).

Browse more upcoming AWS led in-person and virtual developer-focused events.

AWS Community re:Invent re:Caps

Lastly, if you want to learn about top announcements and innovations from AWS re:Invent, the AWS Community shares a summary from a community perspective of these announcements so you can get up to speed. Download the AWS Community re:Invent re:Caps deck. 

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Donnie

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

DeepSeek-R1 models now available on AWS

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-r1-models-now-available-on-aws/

During this past AWS re:Invent, Amazon CEO Andy Jassy shared valuable lessons learned from Amazon’s own experience developing nearly 1,000 generative AI applications across the company. Drawing from this extensive scale of AI deployment, Jassy offered three key observations that have shaped Amazon’s approach to enterprise AI implementation.

First is that as you get to scale in generative AI applications, the cost of compute really matters. People are very hungry for better price performance. The second is actually quite difficult to build a really good generative AI application. The third is the diversity of the models being used when we gave our builders freedom to pick what they want to do. It doesn’t surprise us, because we keep learning the same lesson over and over and over again, which is that there is never going to be one tool to rule the world.

As Andy emphasized, a broad and deep range of models provided by Amazon empowers customers to choose the precise capabilities that best serve their unique needs. By closely monitoring both customer needs and technological advancements, AWS regularly expands our curated selection of models to include promising new models alongside established industry favorites. This ongoing expansion of high-performing and differentiated model offerings helps customers stay at the forefront of AI innovation.

This leads us to Chinese AI startup DeepSeek. DeepSeek launched DeepSeek-V3 on December 2024 and subsequently released DeepSeek-R1, DeepSeek-R1-Zero with 671 billion parameters, and DeepSeek-R1-Distill models ranging from 1.5–70 billion parameters on January 20, 2025. They added their vision-based Janus-Pro-7B model on January 27, 2025. The models are publicly available and are reportedly 90-95% more affordable and cost-effective than comparable models. Per Deepseek, their model stands out for its reasoning capabilities, achieved through innovative training techniques such as reinforcement learning.

Today, you can now deploy DeepSeek-R1 models in Amazon Bedrock and Amazon SageMaker AI. Amazon Bedrock is best for teams seeking to quickly integrate pre-trained foundation models through APIs. Amazon SageMaker AI is ideal for organizations that want advanced customization, training, and deployment, with access to the underlying infrastructure. Additionally, you can also use AWS Trainium and AWS Inferentia to deploy DeepSeek-R1-Distill models cost-effectively via Amazon Elastic Compute Cloud (Amazon EC2) or Amazon SageMaker AI.

With AWS, you can use DeepSeek-R1 models to build, experiment, and responsibly scale your generative AI ideas by using this powerful, cost-efficient model with minimal infrastructure investment. You can also confidently drive generative AI innovation by building on AWS services that are uniquely designed for security. We highly recommend integrating your deployments of the DeepSeek-R1 models with Amazon Bedrock Guardrails to add a layer of protection for your generative AI applications, which can be used by both Amazon Bedrock and Amazon SageMaker AI customers.

You can choose how to deploy DeepSeek-R1 models on AWS today in a few ways: 1/ Amazon Bedrock Marketplace for the DeepSeek-R1 model, 2/ Amazon SageMaker JumpStart for the DeepSeek-R1 model, 3/ Amazon Bedrock Custom Model Import for the DeepSeek-R1-Distill models, and 4/ Amazon EC2 Trn1 instances for the DeepSeek-R1-Distill models.

Let me walk you through the various paths for getting started with DeepSeek-R1 models on AWS. Whether you’re building your first AI application or scaling existing solutions, these methods provide flexible starting points based on your team’s expertise and requirements.

1. The DeepSeek-R1 model in Amazon Bedrock Marketplace
Amazon Bedrock Marketplace offers over 100 popular, emerging, and specialized FMs alongside the current selection of industry-leading models in Amazon Bedrock. You can easily discover models in a single catalog, subscribe to the model, and then deploy the model on managed endpoints.

To access the DeepSeek-R1 model in Amazon Bedrock Marketplace, go to the Amazon Bedrock console and select Model catalog under the Foundation models section. You can quickly find DeepSeek by searching or filtering by model providers.

After checking out the model detail page including the model’s capabilities, and implementation guidelines, you can directly deploy the model by providing an endpoint name, choosing the number of instances, and selecting an instance type.

You can also configure advanced options that let you customize the security and infrastructure settings for the DeepSeek-R1 model including VPC networking, service role permissions, and encryption settings. For production deployments, you should review these settings to align with your organization’s security and compliance requirements.

With Amazon Bedrock Guardrails, you can independently evaluate user inputs and model outputs. You can control the interaction between users and DeepSeek-R1 with your defined set of policies by filtering undesirable and harmful content in generative AI applications. The DeepSeek-R1 model in Amazon Bedrock Marketplace can only be used with Bedrock’s ApplyGuardrail API to evaluate user inputs and model responses for custom and third-party FMs available outside of Amazon Bedrock. To learn more, read Implement model-independent safety measures with Amazon Bedrock Guardrails.

Amazon Bedrock Guardrails can also be integrated with other Bedrock tools including Amazon Bedrock Agents and Amazon Bedrock Knowledge Bases to build safer and more secure generative AI applications aligned with responsible AI policies. To learn more, visit the AWS Responsible AI page.

Refer to this step-by-step guide on how to deploy the DeepSeek-R1 model in Amazon Bedrock Marketplace. To learn more, visit Deploy models in Amazon Bedrock Marketplace.

2. The DeepSeek-R1 model in Amazon SageMaker JumpStart
Amazon SageMaker JumpStart is a machine learning (ML) hub with FMs, built-in algorithms, and prebuilt ML solutions that you can deploy with just a few clicks. To deploy DeepSeek-R1 in SageMaker JumpStart, you can discover the DeepSeek-R1 model in SageMaker Unified Studio, SageMaker Studio, SageMaker AI console, or programmatically through the SageMaker Python SDK.

In the Amazon SageMaker AI console, open SageMaker Unified Studio or SageMaker Studio. In case of SageMaker Studio, choose JumpStart and search for “DeepSeek-R1” in the All public models page.

You can select the model and choose deploy to create an endpoint with default settings. When the endpoint comes InService, you can make inferences by sending requests to its endpoint.

You can derive model performance and ML operations controls with Amazon SageMaker AI features such as Amazon SageMaker Pipelines, Amazon SageMaker Debugger, or container logs. The model is deployed in an AWS secure environment and under your virtual private cloud (VPC) controls, helping to support data security.

As like Bedrock Marketpalce, you can use the ApplyGuardrail API in the SageMaker JumpStart to decouple safeguards for your generative AI applications from the DeepSeek-R1 model. You can now use guardrails without invoking FMs, which opens the door to more integration of standardized and thoroughly tested enterprise safeguards to your application flow regardless of the models used.

Refer to this step-by-step guide on how to deploy DeepSeek-R1 in Amazon SageMaker JumpStart. To learn more, visit Discover SageMaker JumpStart models in SageMaker Unified Studio or Deploy SageMaker JumpStart models in SageMaker Studio.

3. DeepSeek-R1-Distill models using Amazon Bedrock Custom Model Import
Amazon Bedrock Custom Model Import provides the ability to import and use your customized models alongside existing FMs through a single serverless, unified API without the need to manage underlying infrastructure. With Amazon Bedrock Custom Model Import, you can import DeepSeek-R1-Distill Llama models ranging from 1.5–70 billion parameters. As I highlighted in my blog post about Amazon Bedrock Model Distillation, the distillation process involves training smaller, more efficient models to mimic the behavior and reasoning patterns of the larger DeepSeek-R1 model with 671 billion parameters by using it as a teacher model.

After storing these publicly available models in an Amazon Simple Storage Service (Amazon S3) bucket or an Amazon SageMaker Model Registry, go to Imported models under Foundation models in the Amazon Bedrock console and import and deploy them in a fully managed and serverless environment through Amazon Bedrock. This serverless approach eliminates the need for infrastructure management while providing enterprise-grade security and scalability.

Refer to this step-by-step guide on how to deploy DeepSeek-R1 models using Amazon Bedrock Custom Model Import. To learn more, visit Import a customized model into Amazon Bedrock.

4. DeepSeek-R1-Distill models using AWS Trainium and AWS Inferentia
AWS Deep Learning AMIs (DLAMI) provides customized machine images that you can use for deep learning in a variety of Amazon EC2 instances, from a small CPU-only instance to the latest high-powered multi-GPU instances. You can deploy the DeepSeek-R1-Distill models on AWS Trainuim1 or AWS Inferentia2 instances to get the best price-performance.

To get started, go to Amazon EC2 console and launch a trn1.32xlarge EC2 instance with the Neuron Multi Framework DLAMI called Deep Learning AMI Neuron (Ubuntu 22.04).

Once you have connected to your launched ec2 instance, install vLLM, an open-source tool to serve Large Language Models (LLMs) and download the DeepSeek-R1-Distill model from Hugging Face. You can deploy the model using vLLM and invoke the model server.

To learn more, refer to this step-by-step guide on how to deploy DeepSeek-R1-Distill Llama models on AWS Inferentia and Trainium.

You can also visit the DeepSeek-R1-Distill-Llama-8B or deepseek-ai/DeepSeek-R1-Distill-Llama-70B model cards on Hugging Face. Choose Deploy and then Amazon SageMaker. From the AWS Inferentia and Trainium tab, copy the example code for deploy DeepSeek-R1-Distill Llama models.

Since the release of DeepSeek-R1, various guides of its deployment for Amazon EC2 and Amazon Elastic Kubernetes Service (Amazon EKS) have been posted. Here is some additional material for you to check out:

Things to know
Here are a few important things to know.

  • Pricing – For publicly available models like DeepSeek-R1, you are charged only the infrastructure price based on inference instance hours you select for Amazon Bedrock Markeplace, Amazon SageMaker JumpStart, and Amazon EC2. For the Bedrock Custom Model Import, you are only charged for model inference, based on the number of copies of your custom model is active, billed in 5-minute windows. To learn more, check out the Amazon Bedrock Pricing, Amazon SageMaker AI Pricing, and Amazon EC2 Pricing pages.
  • Data security – You can use enterprise-grade security features in Amazon Bedrock and Amazon SageMaker to help you make your data and applications secure and private. This means your data is not shared with model providers, and is not used to improve the models. This applies to all models—proprietary and publicly available—like DeepSeek-R1 models on Amazon Bedrock and Amazon SageMaker. To learn more, visit Amazon Bedrock Security and Privacy and Security in Amazon SageMaker AI.

Now available
DeepSeek-R1 is generally available today in Amazon Bedrock Marketplace and Amazon SageMaker JumpStart. You can also use DeepSeek-R1-Distill models using Amazon Bedrock Custom Model Import and Amazon EC2 instances with AWS Trainum and Inferentia chips.

Give DeepSeek-R1 models a try today in the Amazon Bedrock console, Amazon SageMaker AI console, and Amazon EC2 console, and send feedback to AWS re:Post for Amazon Bedrock and AWS re:Post for SageMaker AI or through your usual AWS Support contacts.

— Channy

AWS Weekly roundup: EventBridge, SNS FIFO, Amazon Corretto, Amazon Connect, Amazon Bedrock, and more

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-eventbridge-sns-fifo-amazon-corretto-amazon-connect-amazon-bedrock-and-more/

I counted about 40 new launches from AWS since last week – back to our normal rhythm of releases. Services teams are listening to your feedback and developing little (or big) changes that makes your life easier when working with our services. The ability to support multiple sessions in the AWS Console is my favorite one so far in 2025.

But our teams didn’t stop there, let’s look at the last week’s new announcements.

Last week’s launches

Beside the usual Regional expansion (new capabilities that are now available in a new Region), here are the launches that got my attention.

Amazon EventBridge announces direct delivery to cross-account targets – Amazon EventBridge is now able to deliver events to targets in another AWS account directly without having to send them to the default bus in the target account first. This will simplify so many architectures out there! It supports any target that supports resource-based policies, including AWS Lambda, Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), Amazon Kinesis, and Amazon API Gateway.

Amazon Corretto quaterly update – We announced quarterly security and critical updates for Amazon Corretto Long-Term Supported (LTS) and Feature Release (FR) versions of OpenJDK. Corretto 23.0.2, 21.0.6, 17.0.14, 11.0.26, 8u442 are now available for download. Amazon Corretto is a no-cost, multi-platform, production-ready distribution of OpenJDK. You can download the updates from the Corretto home page or just type apt-get or yum update.

High-throughput mode for Amazon SNS FIFO Topics – Amazon SNS now supports high-throughput mode for SNS FIFO topics, with default throughput matching SNS standard topics across all Regions. When you enable high-throughput mode, SNS FIFO topics will maintain order within message group, while reducing the deduplication scope to the message-group level. With this change, you can leverage up to 30K messages per second (MPS) per account by default in US East (N. Virginia) Region, and 9K MPS per account in US West (Oregon) and Europe (Ireland) Regions, and request quota increases for additional throughput in any Region.

Amazon Connect agent workspace now supports audio optimization for Citrix and Amazon WorkSpaces virtual desktops – Amazon Connect agent workspace now supports the ability to redirect audio from Citrix and Amazon WorkSpaces Virtual Desktop Infrastructure (VDI) environments to a customer service agent’s local device. Audio redirection improves voice quality and reduces latency for voice calls handled on virtual desktops, providing a better experience for both end customers and agents.

Amazon Redshift announces support for History Mode for zero-ETL integrations – This new capability enables you to build Type 2 Slowly Changing Dimension (SCD 2) tables on your historical data from databases, out-of-the-box in Amazon Redshift, without writing any code. History mode simplifies the process of tracking and analyzing historical data changes, allowing you to gain valuable insights from your data’s evolution over time.

Finally, Amazon Bedrock has its own set of announcements. First, for anyone investing in retrieval-augmented generation, Bedrock now support multimodal content with Cohere Embed 3 Multilingual and Embed 3 English models. This enables you to create embeddings to not only index text, but also images.

Second, read Luma AI’s Ray2 visual AI model now available in Amazon Bedrock. Luma Ray2 is a large-scale video-generation model capable of creating realistic visuals with fluid, natural movement. With Luma Ray2 in Amazon Bedrock, you can generate production-ready video clips with seamless animations, ultrarealistic details, and logical event sequences with natural language prompts, removing the need for technical prompt engineering. Ray2 currently supports 5- and 9-second video generations with 540p and 720p resolution.

And finally, Amazon Bedrock Flows announces preview of multi-turn conversation support. Amazon Bedrock Flows enables you to link foundation models (FMs), Amazon Bedrock Prompts, Amazon Bedrock Agents, Amazon Bedrock Knowledge Bases, Amazon Bedrock Guardrails and other AWS services together to build and scale pre-defined generative AI workflows. This week, the team announced preview of multi-turn conversation support for agent nodes in Flows. This capability enables dynamic, back-and-forth conversations between users and flows, similar to a natural dialogue.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS events
Check your calendar and sign up for upcoming AWS events.

AWS Summits season is starting! I’m already working with the local team to prepare content for the Summits in Paris and London. Summits are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Stay updated by visiting the official AWS Summit website and sign up for notifications to learn when registration opens for events in your area.

AWS GenAI Lofts are collaborative spaces and immersive experiences that showcase AWS expertise in cloud computing and AI. They provide startups and developers with hands-on access to AI products and services, exclusive sessions with industry leaders, and valuable networking opportunities with investors and peers. Find a GenAI Loft location near you, and don’t forget to register.

Browse all upcoming AWS led in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!