Post Syndicated from Explosm.net original https://explosm.net/comics/time-machine
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/time-machine
New Cyanide and Happiness Comic
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=Rfw35kfunqE
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/on-the-need-for-an-ai-public-option.html
Artificial intelligence will bring great benefits to all of humanity. But do we really want to entrust this revolutionary technology solely to a small group of US tech companies?
Silicon Valley has produced no small number of moral disappointments. Google retired its “don’t be evil” pledge before firing its star ethicist. Self-proclaimed “free speech absolutist” Elon Musk bought Twitter in order to censor political speech, retaliate against journalists, and ease access to the platform for Russian and Chinese propagandists. Facebook lied about how it enabled Russian interference in the 2016 US presidential election and paid a public relations firm to blame Google and George Soros instead.
These and countless other ethical lapses should prompt us to consider whether we want to give technology companies further abilities to learn our personal details and influence our day-to-day decisions. Tech companies can already access our daily whereabouts and search queries. Digital devices monitor more and more aspects of our lives: We have cameras in our homes and heartbeat sensors on our wrists sending what they detect to Silicon Valley.
Now, tech giants are developing ever more powerful AI systems that don’t merely monitor you; they actually interact with you—and with others on your behalf. If searching on Google in the 2010s was like being watched on a security camera, then using AI in the late 2020s will be like having a butler. You will willingly include them in every conversation you have, everything you write, every item you shop for, every want, every fear, everything. It will never forget. And, despite your reliance on it, it will be surreptitiously working to further the interests of one of these for-profit corporations.
There’s a reason Google, Microsoft, Facebook, and other large tech companies are leading the AI revolution: Building a competitive large language model (LLM) like the one powering ChatGPT is incredibly expensive. It requires upward of $100 million in computational costs for a single model training run, in addition to access to large amounts of data. It also requires technical expertise, which, while increasingly open and available, remains heavily concentrated in a small handful of companies. Efforts to disrupt the AI oligopoly by funding start-ups are self-defeating as Big Tech profits from the cloud computing services and AI models powering those start-ups—and often ends up acquiring the start-ups themselves.
Yet corporations aren’t the only entities large enough to absorb the cost of large-scale model training. Governments can do it, too. It’s time to start taking AI development out of the exclusive hands of private companies and bringing it into the public sector. The United States needs a government-funded-and-directed AI program to develop widely reusable models in the public interest, guided by technical expertise housed in federal agencies.
So far, the AI regulation debate in Washington has focused on the governance of private-sector activity—which the US Congress is in no hurry to advance. Congress should not only hurry up and push AI regulation forward but also go one step further and develop its own programs for AI. Legislators should reframe the AI debate from one about public regulation to one about public development.
The AI development program could be responsive to public input and subject to political oversight. It could be directed to respond to critical issues such as privacy protection, underpaid tech workers, AI’s horrendous carbon emissions, and the exploitation of unlicensed data. Compared to keeping AI in the hands of morally dubious tech companies, the public alternative is better both ethically and economically. And the switch should take place soon: By the time AI becomes critical infrastructure, essential to large swaths of economic activity and daily life, it will be too late to get started.
Other countries are already there. China has heavily prioritized public investment in AI research and development by betting on a handpicked set of giant companies that are ostensibly private but widely understood to be an extension of the state. The government has tasked Alibaba, Huawei, and others with creating products that support the larger ecosystem of state surveillance and authoritarianism.
The European Union is also aggressively pushing AI development. The European Commission already invests 1 billion euros per year in AI, with a plan to increase that figure to 20 billion euros annually by 2030. The money goes to a continent-wide network of public research labs, universities, and private companies jointly working on various parts of AI. The Europeans’ focus is on knowledge transfer, developing the technology sector, use of AI in public administration, mitigating safety risks, and preserving fundamental rights. The EU also continues to be at the cutting edge of aggressively regulating both data and AI.
Neither the Chinese nor the European model is necessarily right for the United States. State control of private enterprise remains anathema in American political culture and would struggle to gain mainstream traction. The tech companies—and their supporters in both US political parties—are opposed to robust public governance of AI. But Washington can take inspiration from China and Europe’;s long-range planning and leadership on regulation and public investment. With boosters pointing to hundreds of trillions of dollars of global economic value associated with AI, the stakes of international competition are compelling. As in energy and medical research, which have their own federal agencies in the Department of Energy and the National Institutes of Health, respectively, there is a place for AI research and development inside government.
Beside the moral argument against letting private companies develop AI, there’s a strong economic argument in favor of a public option as well. A publicly funded LLM could serve as an open platform for innovation, helping any small business, nonprofit, or individual entrepreneur to build AI-assisted applications.
There’s also a practical argument. Building AI is within public reach because governments don’t need to own and operate the entire AI supply chain. Chip and computer production, cloud data centers, and various value-added applications—such as those that integrate AI with consumer electronics devices or entertainment software—do not need to be publicly controlled or funded.
One reason to be skeptical of public funding for AI is that it might result in a lower quality and slower innovation, given greater ethical scrutiny, political constraints, and fewer incentives due to a lack of market competition. But even if that is the case, it would be worth broader access to the most important technology of the 21st century. And it is by no means certain that public AI has to be at a disadvantage. The open-source community is proof that it’s not always private companies that are the most innovative.
Those who worry about the quality trade-off might suggest a public buyer model, whereby Washington licenses or buys private language models from Big Tech instead of developing them itself. But that doesn’t go far enough to ensure that the tools are aligned with public priorities and responsive to public needs. It would not give the public detailed insight into or control of the inner workings and training procedures for these models, and it would still require strict and complex regulation.
There is political will to take action to develop AI via public, rather than private, funds—but this does not yet equate to the will to create a fully public AI development agency. A task force created by Congress recommended in January a $2.6 billion federal investment in computing and data resources to prime the AI research ecosystem in the United States. But this investment would largely serve to advance the interests of Big Tech, leaving the opportunity for public ownership and oversight unaddressed.
Nonprofit and academic organizations have already created open-access LLMs. While these should be celebrated, they are not a substitute for a public option. Nonprofit projects are still beholden to private interests, even if they are benevolent ones. These private interests can change without public input, as when OpenAI effectively abandoned its nonprofit origins, and we can’t be sure that their founding intentions or operations will survive market pressures, fickle donors, and changes in leadership.
The US government is by no means a perfect beacon of transparency, a secure and responsible store of our data, or a genuine reflection of the public’s interests. But the risks of placing AI development entirely in the hands of demonstrably untrustworthy Silicon Valley companies are too high. AI will impact the public like few other technologies, so it should also be developed by the public.
This essay was written with Nathan Sanders, and appeared in Foreign Policy.
Post Syndicated from original https://lwn.net/Articles/934619/
Security updates have been issued by Debian (ffmpeg, owslib, php7.4, and php8.2), Fedora (ntp-refclock, php, and python3.7), Red Hat (c-ares, firefox, and thunderbird), SUSE (kernel, openldap2, and tomcat), and Ubuntu (binutils, dotnet6, dotnet7, node-fetch, and python-tornado).
Post Syndicated from Екип на Биволъ original https://bivol.bg/korumpeta-geshev.html

Интересно как най-големите корумпета в България изведнъж станаха най-активни борци срещу главния прокурор Иван Гешев. Неслучайно и Висшият съдебен съвет (ВСС) разкри марионетната си същност и зависимост от Мафията, експресно…
Post Syndicated from original https://xkcd.com/2789/
Post Syndicated from David MacDonald original https://aws.amazon.com/blogs/security/prevent-account-creation-fraud-with-aws-waf-fraud-control-account-creation-fraud-prevention/
Threat actors use sign-up pages and login pages to carry out account fraud, including taking unfair advantage of promotional and sign-up bonuses, publishing fake reviews, and spreading malware.
In 2022, AWS released AWS WAF Fraud Control – Account Takeover Prevention (ATP) to help protect your application’s login page against credential stuffing attacks, brute force attempts, and other anomalous login activities.
Today, we introduce AWS WAF Fraud Control – Account Creation Fraud Prevention (ACFP) to help protect your application’s sign-up pages against fake account creation by detecting and blocking fake account creation requests.
You can now get comprehensive account fraud prevention by combining AWS WAF Account Creation Fraud Prevention and Account Takeover Prevention in your AWS WAF web access control list (web ACL). In this post, we will show you how to set up AWS WAF with ACFP for your application sign-up pages.
ACFP helps protect your account sign-up pages by continuously monitoring requests for anomalous digital activity and automatically blocking suspicious requests based on request identifiers, behavioral analysis, and machine learning.
ACFP uses multiple capabilities to help detect and block fake account creation requests at the network edge before they reach your application. An automated vetting process for account creation requests uses rules based on reputation and risk to protect your registration pages against use of stolen credentials and disposable email domains. ACFP uses silent challenges and CAPTCHA challenges to identify and respond to sophisticated bots that are designed to actively evade detection.
ACFP is an AWS Managed Rules rule group. If you already use AWS WAF, you can configure ACFP without making architectural changes. On a single configuration page, you specify the registration page request inspection parameters that ACFP uses to detect fake account creation requests, including user identity, address, and phone number.
ACFP uses session tokens to separate legitimate client sessions from those that are not. These tokens allow ACFP to verify that the client applications that sign up for an account are legitimate. The AWS WAF Javascript SDK automatically generates these tokens during the frontend application load. We recommend that you integrate the AWS WAF Javascript SDK into your application, particularly for single-page applications where you don’t want page refreshes.
In this walkthrough, we will show you how to set up ACFP for AWS WAF to help protect your account sign-up pages against account creation fraud. This walkthrough has two main steps:
The first step is to set up ACFP by creating a web ACL or editing an existing one. You will add the ACFP rule group to this web ACL.
The ACFP rule group requires that you provide your registration page path, account creation path, and optionally the sign-up request fields that map to user identity, address, and phone number. ACFP uses this configuration to detect fraudulent sign-up requests and then decide an appropriate action, including blocking, challenging interstitial during the frontend application load, or requiring a CAPTCHA.

Figure 1: Account creation fraud prevention – Add account creation paths

Figure 2: Account creation fraud prevention – Add optional field names

Figure 3: Account creation fraud prevention – Select actions for each category
The next step is to find the AWS WAF JavaScript SDK and add it to your application pages.
The SDK injects a token in the requests that you send to your protected resources. You must use the SDK integration to fully enable ACFP detections.

Figure 4: Application integration – Add JavaScript SDK link to application pages
<head> section of the HTML. For ACFP, you only need to add the code snippet to the registration page, but if you are using other AWS WAF managed rules such as Account Takeover Protection or Targeted Bots on other pages, you will also need to add the code snippet to those pages.aws-waf-token has been set during page load.Now that you’ve set up the web ACL and integrated the SDK with the application, you can use the bot visualization dashboard in AWS WAF to review fraudulent account creation traffic patterns. ACFP rules emit metrics that correspond to their labels, helping you identify which rule within the ACFP rule group initiated an action. You can also use labels and rule actions to filter AWS WAF logs so that you can further examine a request.

Figure 5: Account creation fraud prevention – Review web ACL metrics
In this section, we share best practices for your ACFP rule group setup.
ACFP evaluates web ACL rules in priority order and takes the action associated with the first rule that a request matches. Requests that match and are blocked by a rule will not be evaluated against lower priority rules. ACFP only evaluates an ACFP rule group if a request matches the registration and account creation URI paths that are specified in the configuration.
You will incur additional fees for requests that ACFP evaluates. To help reduce ACFP costs, use higher priority rules to block requests before the ACFP rule group evaluates them. For example, you can add a higher priority AWS Managed Rules IP reputation rule group to block account creation requests from bots and other threats before ACFP evaluates them. Rate-based rules with a higher priority than the ACFP rule group can help mitigate volumetric account creation attempts by limiting the number of requests that a single IP can make in a five-minute period. For further guidance on rate-based rules, see The three most important AWS WAF rate-based rules.
If you are using the AWS WAF Bot Control rule group, give it a higher priority than the ACFP rule group because it’s less expensive to evaluate.
ACFP requires the tokens that the SDK generates. The SDK can generate these tokens silently rather than requiring a redirect or CAPTCHA. Both AWS WAF Bot Control and AWS WAF Fraud Control use the same SDK if both rule groups are in the same web ACL.
These tokens have a default immunity time (otherwise knowns as a timeout) of 5 minutes, after which AWS WAF requires the client to be challenged again. You can use the AWS WAF integration fetch wrapper in your single-pane application to help ensure that the token retrieval completes before the client sends requests to your account creation API without requiring a page refresh. Alternatively, you can use the getToken operation if you are not using fetch.
You can continue to use the CAPTCHA JavaScript API instead if you’ve already integrated this into your application.
You can help prevent account fraud for both sign-up and login pages by enabling the ATP rule group in the same web ACL as ACFP.
Test and tune your ACFP implementation in a staging or testing environment to help avoid negatively impacting legitimate users. We recommend that you start by deploying your rules in count mode in production to understand potential impact to your traffic before switching them back to the default rule actions. Use the default ACFP rule group actions when you deploy the web ACL to production. For further guidance, see Testing and Deploying ACFP.
ACFP is available today on Amazon CloudFront and in 22 AWS Regions. For information on availability and pricing, see AWS WAF Pricing.
In this post, we showed you how to use ACFP to protect your application’s sign-up pages against fake account creation. You can now combine ACFP with ATP managed rules in a single web ACL for comprehensive account fraud prevention. For more information and to get started today, see the AWS WAF Developer Guide.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Post Syndicated from Adam Barnett original https://blog.rapid7.com/2023/06/13/patch-tuesday-june-2023/
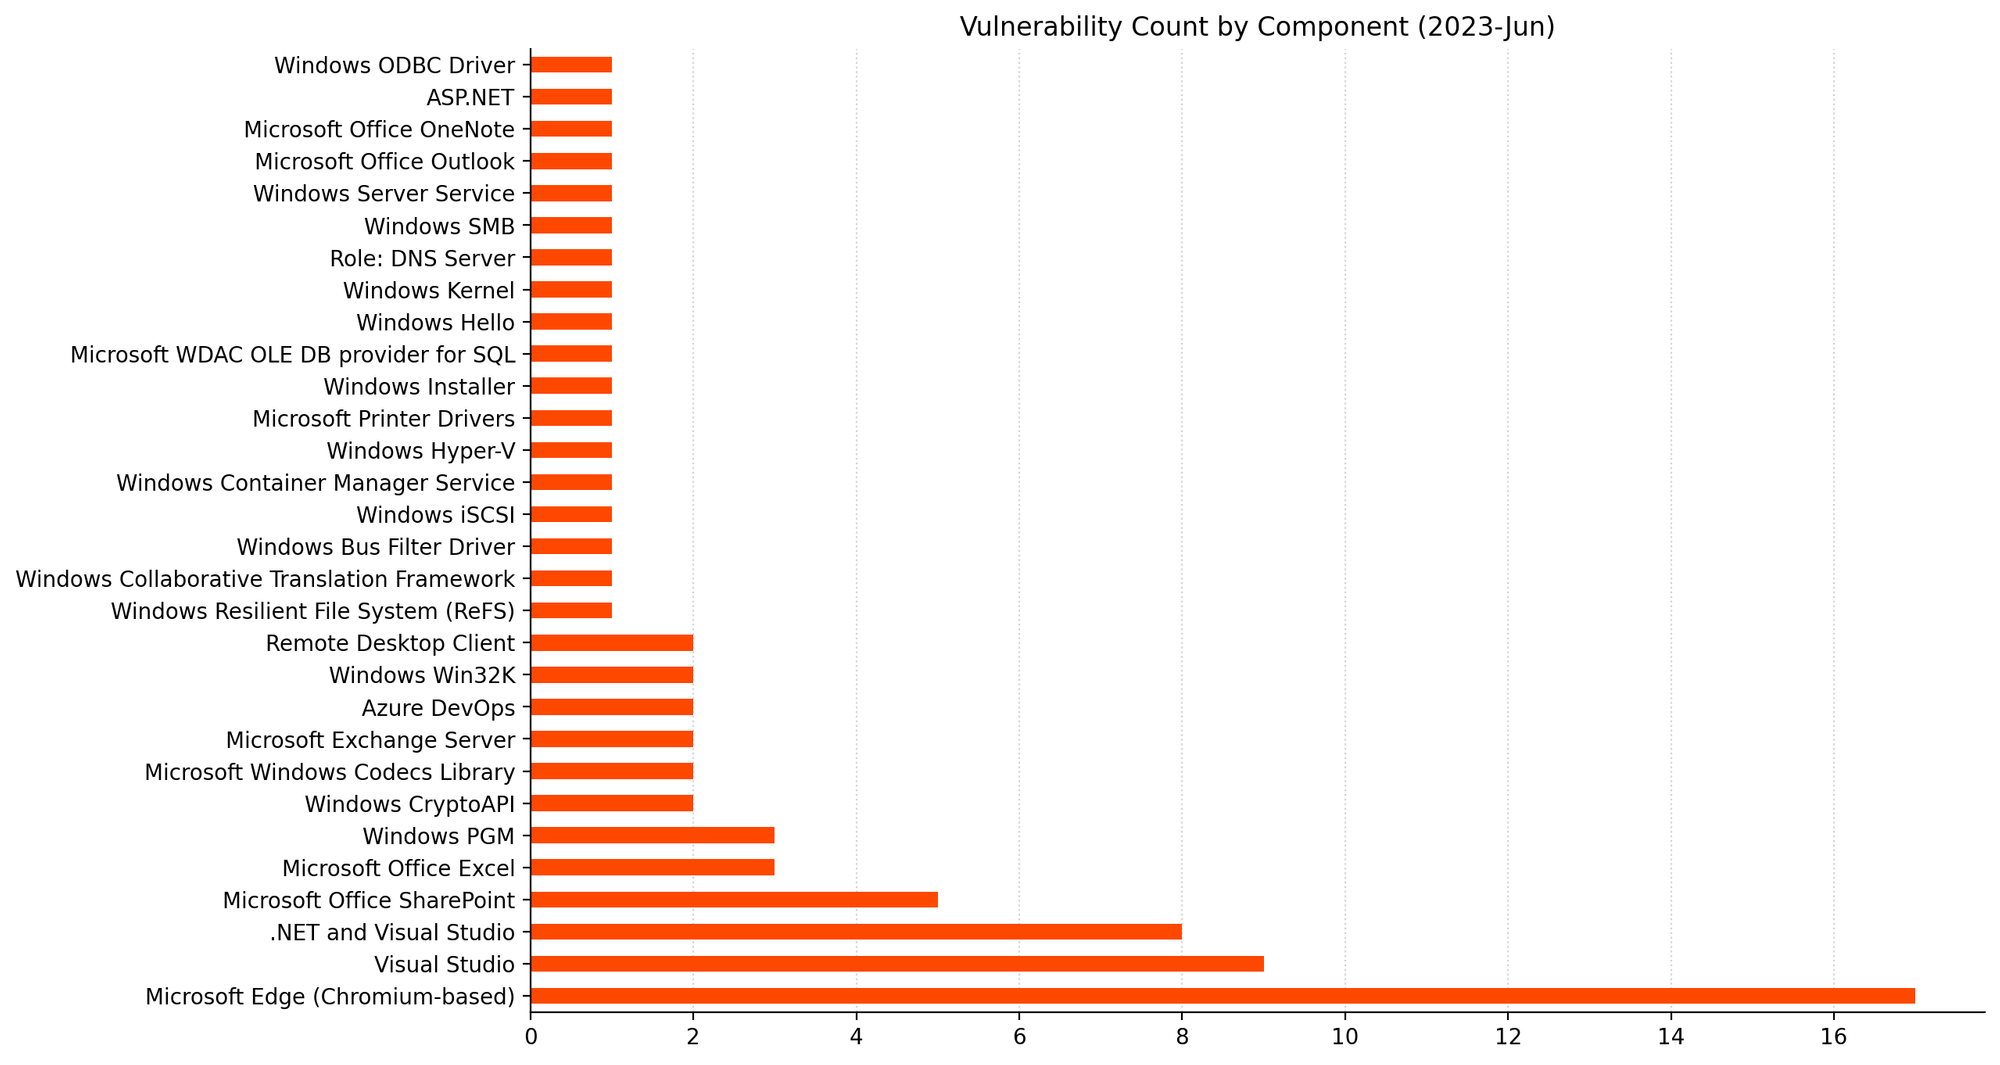
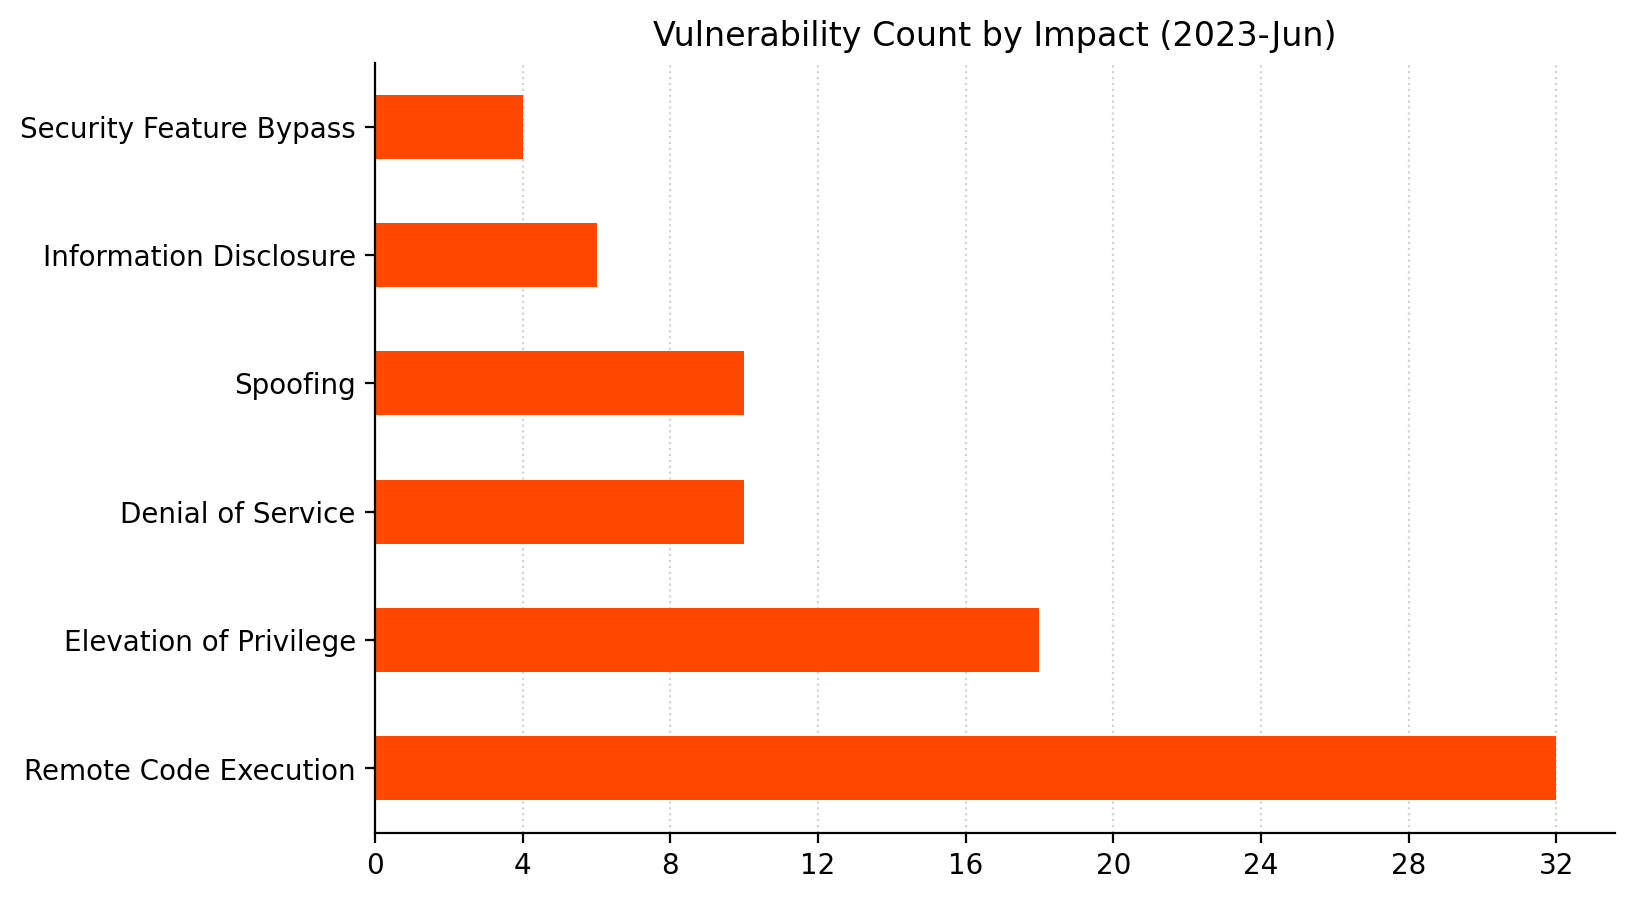
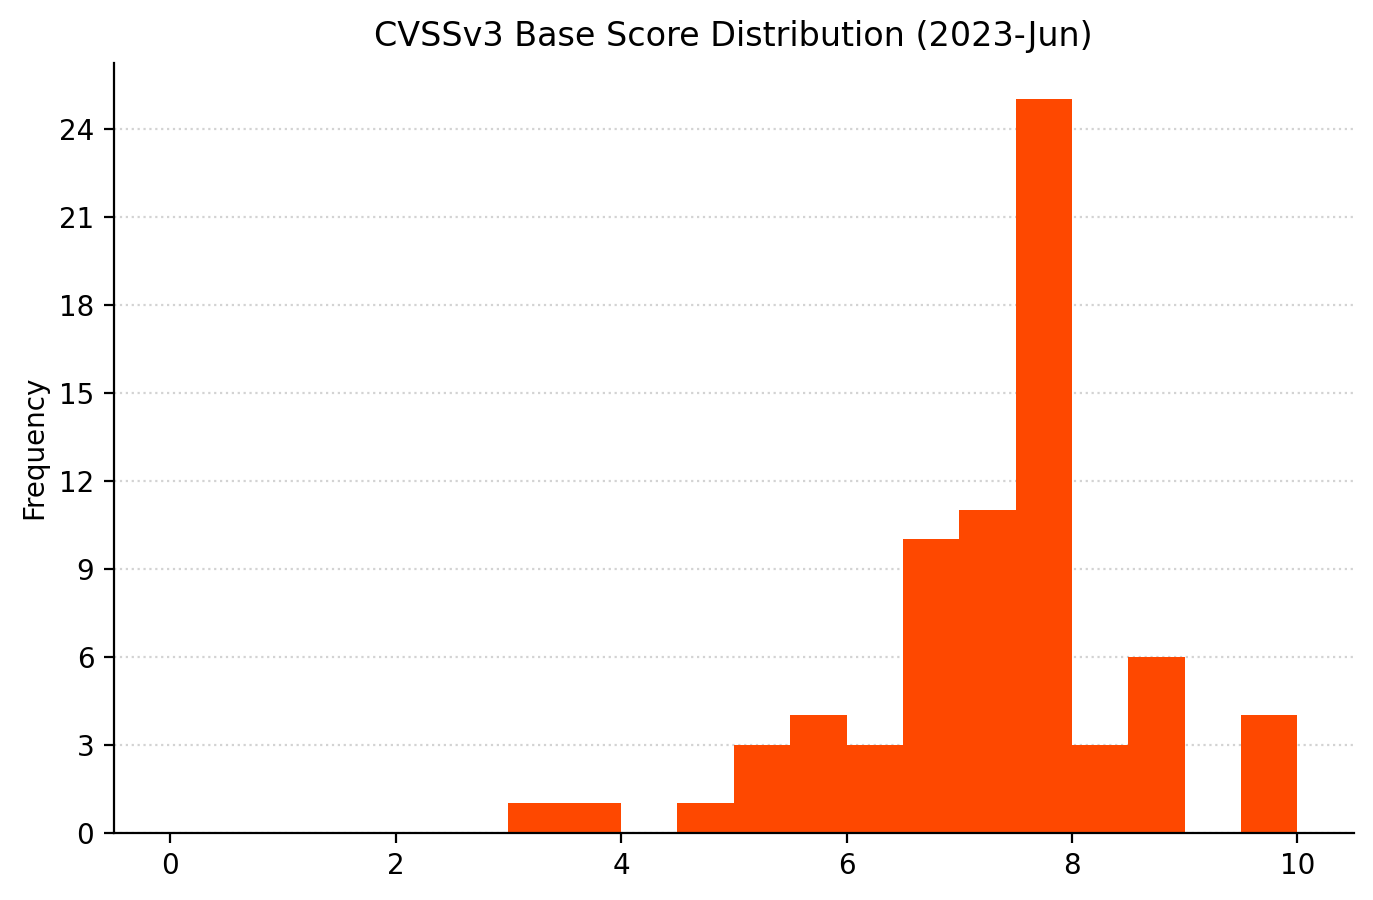
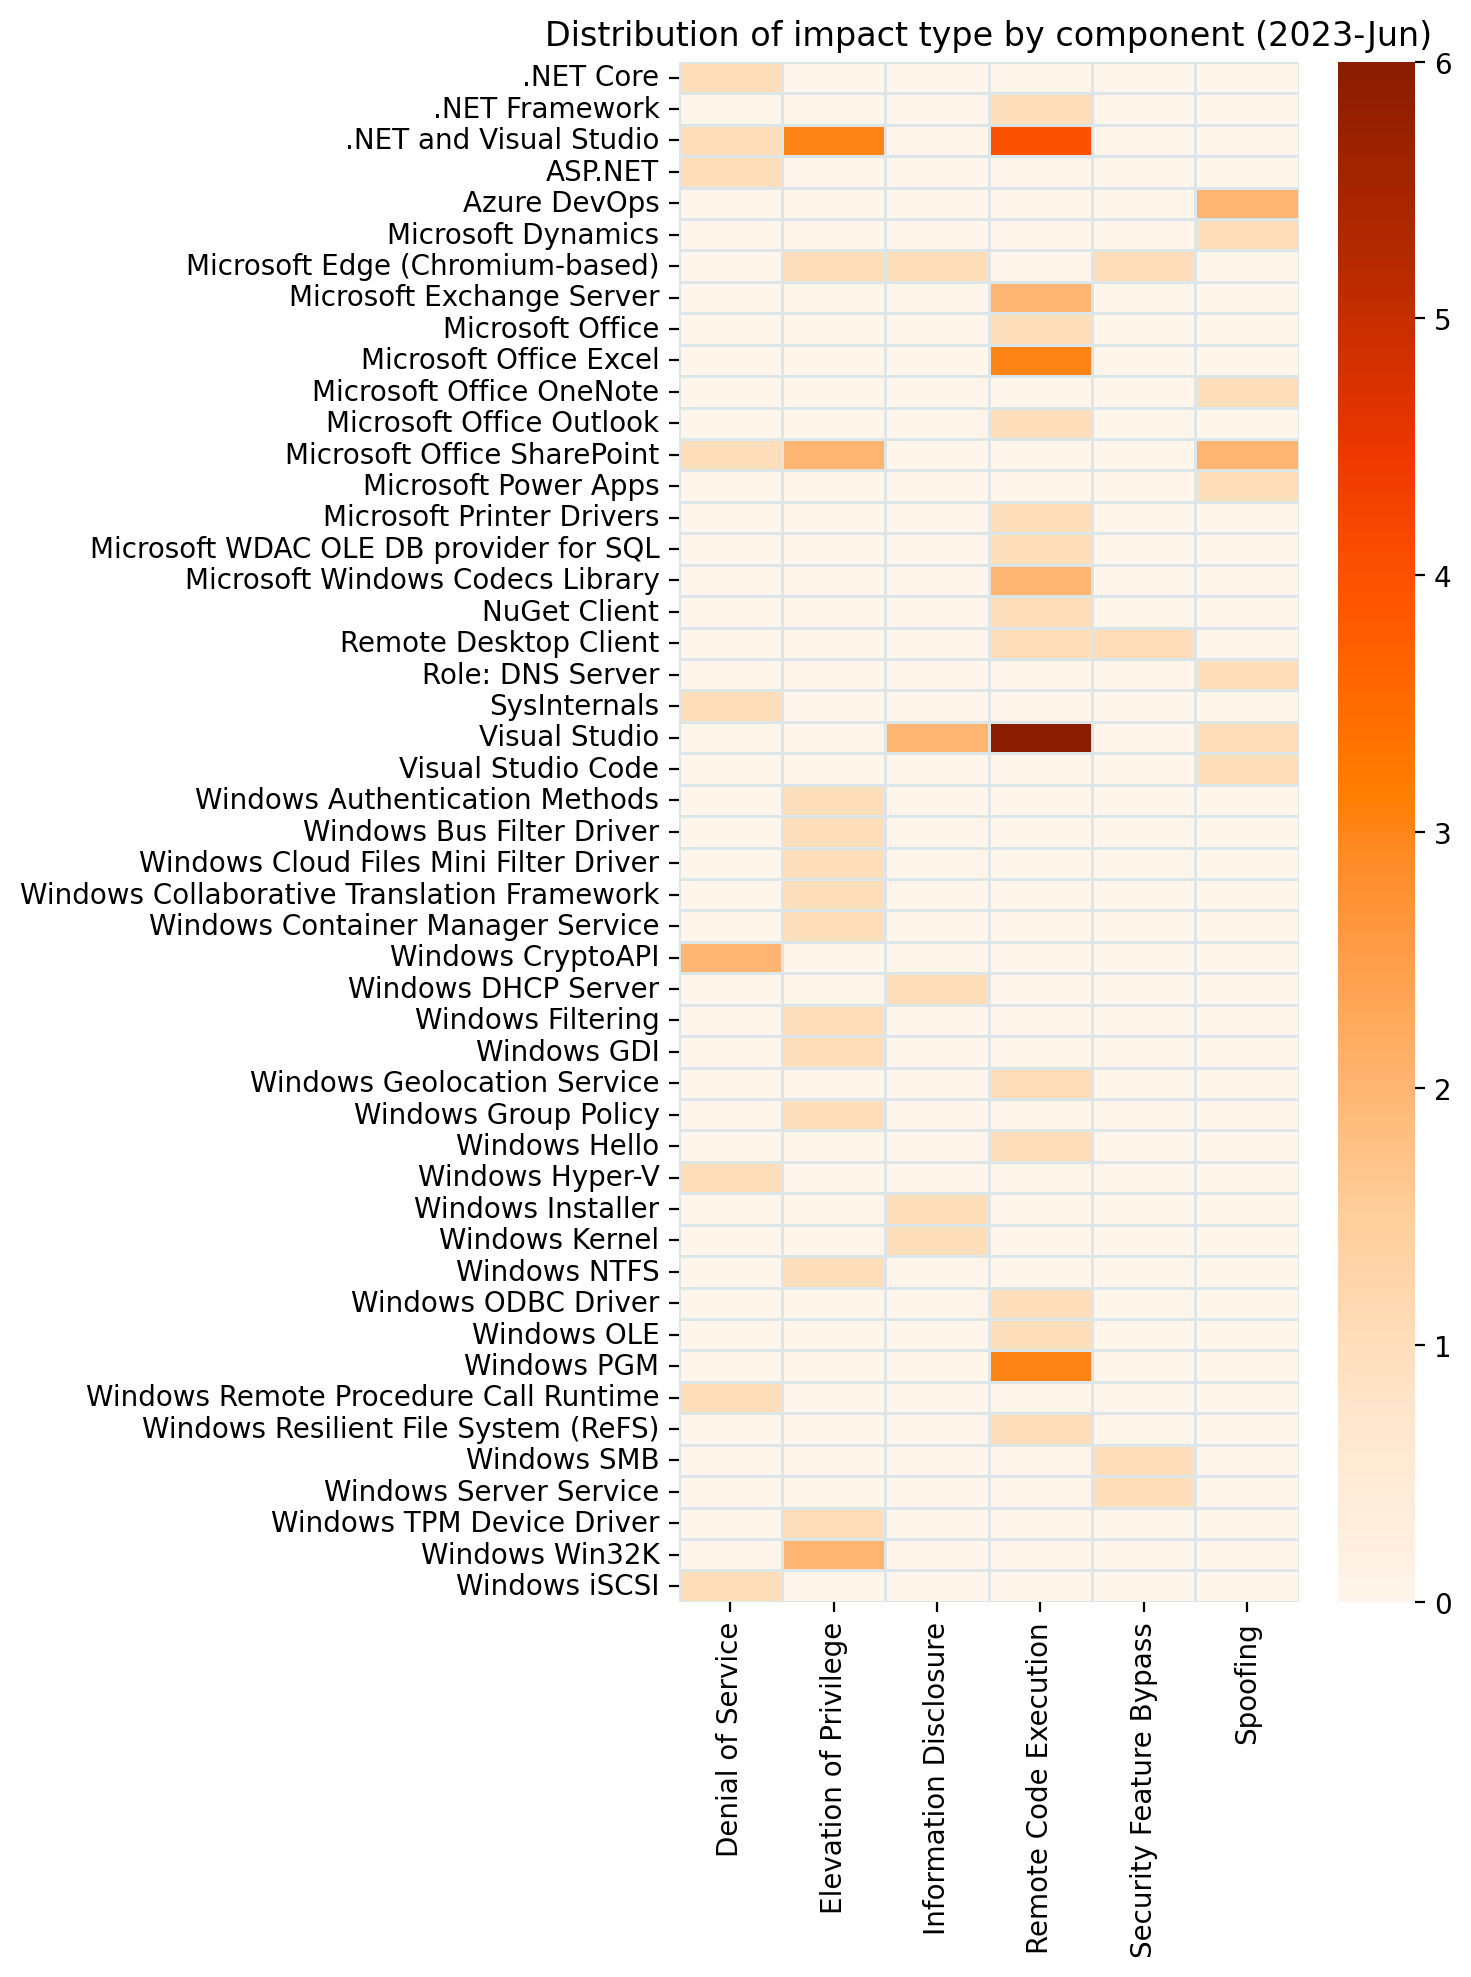
It’s June, and it’s Patch Tuesday. The volume of fixes this month is typical compared with recent history: 94 in total (including Edge-on-Chromium). For the first time in a while, Microsoft isn’t offering patches for any zero-day vulnerabilities, but we do get fixes for four critical Remote Code Execution (RCE) vulnerabilities: one in .NET/Visual Studio, and three in Windows Pragmatic General Multicast (PGM). Also patched: a critical SharePoint Elevation of Privilege vulnerability.
SharePoint administrators should start by looking at critical Elevation of Privilege vulnerability CVE-2023-29357, which provides attackers with a chance at Administrator privileges on the SharePoint host, provided they come prepared with spoofed JWT tokens. Microsoft isn’t aware of public disclosure or in-the-wild exploitation, but considers exploitation more likely.
The FAQ provided with Microsoft’s advisory suggests that both SharePoint Enterprise Server 2016 and SharePoint Server 2019 are vulnerable. So far so good for SharePoint 2019, but there is a lack of clarity around a patch for SharePoint 2016.
Initially, neither the advisory nor the SharePoint 2016 Release history listed a relevant patch for SharePoint 2016. Microsoft has since updated both the SharePoint 2016 release history to include a link to the June security update for SharePoint Enterprise Server 2016; however, the link incorrectly points to the May advisory, and should instead point to the June 2023 security update for SharePoint 2016 KB5002404.
Complicating matters further, KB5002404 does not mention CVE-2023-29357, and the advisory for CVE-2023-29357 still does not mention any patch for SharePoint 2016. Defenders responsible for SharePoint 2016 will no doubt wish to follow developments here closely; on present evidence, the only safe assumption is that there is no patch yet which addresses CVE-2023-29357 for SharePoint 2016.
Microsoft also mentions that there may be more than one patch listed for a particular version of SharePoint, and that every patch for a particular version of SharePoint must be installed to remediate this vulnerability (although order of patching doesn’t matter).
This is the third month in a row where Patch Tuesday features at least one critical RCE in Windows PGM, and June adds three to the pile. Microsoft hasn’t detected exploitation or disclosure for any of these, and considers exploitation less likely, but a trio of critical RCEs with CVSS 3.1 base score of 9.8 will deservedly attract a degree of attention.
All three PGM critical RCEs – CVE-2023-29363, CVE-2023-32014, and CVE-2023-32015 – require an attacker to send a specially-crafted file over the network in the hope of executing malicious code on the target asset. Defenders who successfully navigated last month’s batch of PGM vulnerabilities will find both risk profile and mitigation/remediation guidance very similar; indeed, CVE-2023-29363 was reported to Microsoft by the same researcher as last month’s CVE-2023-28250.
As with previous similar vulnerabilities, Windows Message Queueing Service (MSMQ) must be enabled for an asset to be exploitable, and MSMQ isn’t enabled by default. As Rapid7 has noted previously, however, a number of applications – including Microsoft Exchange – quietly introduce MSMQ as part of their own installation routine. With several prolific researchers active in this area, we should expect further PGM vulnerabilities in the future.
Rounding out this month’s critical RCE list is CVE-2023-24897: a flaw in .NET, .NET Framework and Visual Studio. Exploitation requires an attacker to convince the victim to open a specially-crafted malicious file, typically from a website.
Although Microsoft has no knowledge of public disclosure or exploitation in the wild, and considers exploitation less likely, the long list of patches – going back as far as .NET Framework 3.5 on Windows 10 1607 – means that this vulnerability has been present for years. Somewhat unusually for this class of vulnerability, Microsoft doesn’t give any indication of filetype. However, the Arbitrary Code Execution (ACE) boilerplate qualifier is present: “remote” refers here to the location of the attacker, rather than the attack, since local user interaction is required.
After a brief reprieve last month, Exchange admins will want to patch a pair of RCE vulnerabilities this month. While neither CVE-2023-28310 nor CVE-2023-32031 quite manages to rank as critical vulnerabilities, either via CVSSv3 base score, or via Microsoft’s proprietary severity scale, they’re not far off. Only the requirement that the attacker has previously achieved an authenticated role on the Exchange server prevents these vulnerabilities from scoring higher – but that’s just the sort of issue that exploit chains are designed to overcome.
Microsoft expects to see exploitation for both of these vulnerabilities. Successful exploitation will make use of PowerShell remoting sessions to achieve remote code execution.
A vulnerability in Azure DevOps server could lead to an attacker accessing detailed data such as organization/project configuration, groups, teams, projects, pipelines, boards, and wiki. CVE-2023-21565 requires an attacker to have existing valid credentials for the service, but no elevated privilege is required. The advisory lists patches for 2020.1.2, 2022 and 2022.0.1.
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-33143 | Microsoft Edge (Chromium-based) Elevation of Privilege Vulnerability | No | No | 7.5 |
| CVE-2023-33145 | Microsoft Edge (Chromium-based) Information Disclosure Vulnerability | No | No | 6.5 |
| CVE-2023-29345 | Microsoft Edge (Chromium-based) Security Feature Bypass Vulnerability | No | No | 6.1 |
| CVE-2023-3079 | Chromium: CVE-2023-3079 Type Confusion in V8 | No | No | N/A |
| CVE-2023-2941 | Chromium: CVE-2023-2941 Inappropriate implementation in Extensions API | No | No | N/A |
| CVE-2023-2940 | Chromium: CVE-2023-2940 Inappropriate implementation in Downloads | No | No | N/A |
| CVE-2023-2939 | Chromium: CVE-2023-2939 Insufficient data validation in Installer | No | No | N/A |
| CVE-2023-2938 | Chromium: CVE-2023-2938 Inappropriate implementation in Picture In Picture | No | No | N/A |
| CVE-2023-2937 | Chromium: CVE-2023-2937 Inappropriate implementation in Picture In Picture | No | No | N/A |
| CVE-2023-2936 | Chromium: CVE-2023-2936 Type Confusion in V8 | No | No | N/A |
| CVE-2023-2935 | Chromium: CVE-2023-2935 Type Confusion in V8 | No | No | N/A |
| CVE-2023-2934 | Chromium: CVE-2023-2934 Out of bounds memory access in Mojo | No | No | N/A |
| CVE-2023-2933 | Chromium: CVE-2023-2933 Use after free in PDF | No | No | N/A |
| CVE-2023-2932 | Chromium: CVE-2023-2932 Use after free in PDF | No | No | N/A |
| CVE-2023-2931 | Chromium: CVE-2023-2931 Use after free in PDF | No | No | N/A |
| CVE-2023-2930 | Chromium: CVE-2023-2930 Use after free in Extensions | No | No | N/A |
| CVE-2023-2929 | Chromium: CVE-2023-2929 Out of bounds write in Swiftshader | No | No | N/A |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-24936 | .NET, .NET Framework, and Visual Studio Elevation of Privilege Vulnerability | No | No | 8.1 |
| CVE-2023-24897 | .NET, .NET Framework, and Visual Studio Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-24895 | .NET, .NET Framework, and Visual Studio Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-29326 | .NET Framework Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-33141 | Yet Another Reverse Proxy (YARP) Denial of Service Vulnerability | No | No | 7.5 |
| CVE-2023-29331 | .NET, .NET Framework, and Visual Studio Denial of Service Vulnerability | No | No | 7.5 |
| CVE-2023-32030 | .NET and Visual Studio Denial of Service Vulnerability | No | No | 7.5 |
| CVE-2023-33126 | .NET and Visual Studio Remote Code Execution Vulnerability | No | No | 7.3 |
| CVE-2023-33128 | .NET and Visual Studio Remote Code Execution Vulnerability | No | No | 7.3 |
| CVE-2023-33135 | .NET and Visual Studio Elevation of Privilege Vulnerability | No | No | 7.3 |
| CVE-2023-29337 | NuGet Client Remote Code Execution Vulnerability | No | No | 7.1 |
| CVE-2023-32032 | .NET and Visual Studio Elevation of Privilege Vulnerability | No | No | 6.5 |
| CVE-2023-33139 | Visual Studio Information Disclosure Vulnerability | No | No | 5.5 |
| CVE-2023-29353 | Sysinternals Process Monitor for Windows Denial of Service Vulnerability | No | No | 5.5 |
| CVE-2023-33144 | Visual Studio Code Spoofing Vulnerability | No | No | 5 |
| CVE-2023-29012 | GitHub: CVE-2023-29012 Git CMD erroneously executes doskey.exe in current directory, if it exists |
No | No | N/A |
| CVE-2023-29011 | GitHub: CVE-2023-29011 The config file of connect.exe is susceptible to malicious placing |
No | No | N/A |
| CVE-2023-29007 | GitHub: CVE-2023-29007 Arbitrary configuration injection via git submodule deinit |
No | No | N/A |
| CVE-2023-25815 | GitHub: CVE-2023-25815 Git looks for localized messages in an unprivileged place | No | No | N/A |
| CVE-2023-25652 | GitHub: CVE-2023-25652 "git apply –reject" partially-controlled arbitrary file write | No | No | N/A |
| CVE-2023-27911 | AutoDesk: CVE-2023-27911 Heap buffer overflow vulnerability in Autodesk® FBX® SDK 2020 or prior | No | No | N/A |
| CVE-2023-27910 | AutoDesk: CVE-2023-27910 stack buffer overflow vulnerability in Autodesk® FBX® SDK 2020 or prior | No | No | N/A |
| CVE-2023-27909 | AutoDesk: CVE-2023-27909 Out-Of-Bounds Write Vulnerability in Autodesk® FBX® SDK 2020 or prior | No | No | N/A |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-21565 | Azure DevOps Server Spoofing Vulnerability | No | No | 7.1 |
| CVE-2023-21569 | Azure DevOps Server Spoofing Vulnerability | No | No | 5.5 |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-29363 | Windows Pragmatic General Multicast (PGM) Remote Code Execution Vulnerability | No | No | 9.8 |
| CVE-2023-32014 | Windows Pragmatic General Multicast (PGM) Remote Code Execution Vulnerability | No | No | 9.8 |
| CVE-2023-32015 | Windows Pragmatic General Multicast (PGM) Remote Code Execution Vulnerability | No | No | 9.8 |
| CVE-2023-29362 | Remote Desktop Client Remote Code Execution Vulnerability | No | No | 8.8 |
| CVE-2023-29372 | Microsoft WDAC OLE DB provider for SQL Server Remote Code Execution Vulnerability | No | No | 8.8 |
| CVE-2023-29373 | Microsoft ODBC Driver Remote Code Execution Vulnerability | No | No | 8.8 |
| CVE-2023-29351 | Windows Group Policy Elevation of Privilege Vulnerability | No | No | 8.1 |
| CVE-2023-29365 | Windows Media Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-29358 | Windows GDI Elevation of Privilege Vulnerability | No | No | 7.8 |
| CVE-2023-29371 | Windows GDI Elevation of Privilege Vulnerability | No | No | 7.8 |
| CVE-2023-29346 | NTFS Elevation of Privilege Vulnerability | No | No | 7.8 |
| CVE-2023-32017 | Microsoft PostScript Printer Driver Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-29359 | GDI Elevation of Privilege Vulnerability | No | No | 7.8 |
| CVE-2023-32011 | Windows iSCSI Discovery Service Denial of Service Vulnerability | No | No | 7.5 |
| CVE-2023-29368 | Windows Filtering Platform Elevation of Privilege Vulnerability | No | No | 7 |
| CVE-2023-29364 | Windows Authentication Elevation of Privilege Vulnerability | No | No | 7 |
| CVE-2023-32016 | Windows Installer Information Disclosure Vulnerability | No | No | 5.5 |
| CVE-2023-32020 | Windows DNS Spoofing Vulnerability | No | No | 3.7 |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-32031 | Microsoft Exchange Server Remote Code Execution Vulnerability | No | No | 8.8 |
| CVE-2023-28310 | Microsoft Exchange Server Remote Code Execution Vulnerability | No | No | 8 |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-24896 | Dynamics 365 Finance Spoofing Vulnerability | No | No | 5.4 |
| CVE-2023-32024 | Microsoft Power Apps Spoofing Vulnerability | No | No | 3 |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-29357 | Microsoft SharePoint Server Elevation of Privilege Vulnerability | No | No | 9.8 |
| CVE-2023-33131 | Microsoft Outlook Remote Code Execution Vulnerability | No | No | 8.8 |
| CVE-2023-33146 | Microsoft Office Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-32029 | Microsoft Excel Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-33137 | Microsoft Excel Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-33133 | Microsoft Excel Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-33130 | Microsoft SharePoint Server Spoofing Vulnerability | No | No | 7.3 |
| CVE-2023-33142 | Microsoft SharePoint Server Elevation of Privilege Vulnerability | No | No | 6.5 |
| CVE-2023-33129 | Microsoft SharePoint Denial of Service Vulnerability | No | No | 6.5 |
| CVE-2023-33140 | Microsoft OneNote Spoofing Vulnerability | No | No | 6.5 |
| CVE-2023-33132 | Microsoft SharePoint Server Spoofing Vulnerability | No | No | 6.3 |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score |
|---|---|---|---|---|
| CVE-2023-32009 | Windows Collaborative Translation Framework Elevation of Privilege Vulnerability | No | No | 8.8 |
| CVE-2023-29367 | iSCSI Target WMI Provider Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-29360 | Windows TPM Device Driver Elevation of Privilege Vulnerability | No | No | 7.8 |
| CVE-2023-32008 | Windows Resilient File System (ReFS) Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-29370 | Windows Media Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-32018 | Windows Hello Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-29366 | Windows Geolocation Service Remote Code Execution Vulnerability | No | No | 7.8 |
| CVE-2023-32022 | Windows Server Service Security Feature Bypass Vulnerability | No | No | 7.6 |
| CVE-2023-32021 | Windows SMB Witness Service Security Feature Bypass Vulnerability | No | No | 7.1 |
| CVE-2023-29361 | Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability | No | No | 7 |
| CVE-2023-32010 | Windows Bus Filter Driver Elevation of Privilege Vulnerability | No | No | 7 |
| CVE-2023-29352 | Windows Remote Desktop Security Feature Bypass Vulnerability | No | No | 6.5 |
| CVE-2023-32013 | Windows Hyper-V Denial of Service Vulnerability | No | No | 6.5 |
| CVE-2023-24937 | Windows CryptoAPI Denial of Service Vulnerability | No | No | 6.5 |
| CVE-2023-24938 | Windows CryptoAPI Denial of Service Vulnerability | No | No | 6.5 |
| CVE-2023-29369 | Remote Procedure Call Runtime Denial of Service Vulnerability | No | No | 6.5 |
| CVE-2023-32012 | Windows Container Manager Service Elevation of Privilege Vulnerability | No | No | 6.3 |
| CVE-2023-29355 | DHCP Server Service Information Disclosure Vulnerability | No | No | 5.3 |
| CVE-2023-32019 | Windows Kernel Information Disclosure Vulnerability | No | No | 4.7 |
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=N335-Bhhvkg
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/amd-instinct-mi300-is-the-chance-to-chip-into-nvidia-ai-share/
The AMD Instinct MI300 is a family of CPU and GPU offerings that embodies a next-generation approach for AI and high-performance computing
The post AMD Instinct MI300 is THE Chance to Chip into NVIDIA AI Share appeared first on ServeTheHome.
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/amd-epyc-bergamo-launched-128-cores-per-socket-and-1024-threads-per-1u/
The new AMD EPYC Bergamo will have 128 cores, 256 threads per socket meaning a common 2U 4-node platform will have 2048 threads
The post AMD EPYC Bergamo Launched 128 Cores Per Socket and 1024 Threads Per 1U appeared first on ServeTheHome.
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/amd-genoa-x-the-1-1gb-l3-cache-cpu-launched/
AMD EPYC Genoa-X is a 1.1GB L3 cache part designed for high-performance computing with massive performance gains in some applications
The post AMD Genoa-X The 1.1GB L3 Cache CPU Launched appeared first on ServeTheHome.
Post Syndicated from Stuart Gregg original https://aws.amazon.com/blogs/security/aws-security-hub-launches-a-new-capability-for-automating-actions-to-update-findings/
If you’ve had discussions with a security organization recently, there’s a high probability that the word automation has come up. As organizations scale and consume the benefits the cloud has to offer, it’s important to factor in and understand how the additional cloud footprint will affect operations. Automation is a key enabler for efficient operations and can help drive down the number of repetitive tasks that the operational teams have to perform.
Alert fatigue is caused when humans work on the same repetitive tasks day in and day out and also have a large volume of alerts that need to be addressed. The repetitive nature of these tasks can cause analysts to become numb to the importance of the task or make errors due to manual processing. This can lead to misclassification of security alerts or higher-severity alerts being overlooked due to investigation times. Automation is key here to reduce the number of repetitive tasks and give analysts time to focus on other areas of importance.
In this blog post, we’ll walk you through new capabilities within AWS Security Hub that you can use to take automated actions to update findings. We’ll show you some example scenarios that use this capability and set you up with the knowledge you need to get started with creating automation rules.
AWS Security Hub is available globally and is designed to give you a comprehensive view of your security posture across your AWS accounts. With Security Hub, you have a single place that aggregates, organizes, and prioritizes your security alerts, or findings, from multiple AWS services, including Amazon GuardDuty, Amazon Inspector, Amazon Macie, AWS Firewall Manager, AWS Systems Manager Patch Manager, AWS Config, AWS Health, and AWS Identity and Access Management (IAM) Access Analyzer, as well as from over 65 AWS Partner Network (APN) solutions.
Previously, Security Hub could take automated actions on findings, but this involved going to the Amazon EventBridge console or API, creating an EventBridge rule, and then building an AWS Lambda function, an AWS Systems Manager Automation runbook, or an AWS Step Functions step as the target of that rule. If you wanted to set up these automated actions in the administrator account and home AWS Region and run them in member accounts and in linked Regions, you would also need to deploy the correct IAM permissions to enable the actions to run across accounts and Regions. After setting up the automation flow, you would need to maintain the EventBridge rule, Lambda function, and IAM roles. Such maintenance could include upgrading the Lambda versions, verifying operational efficiency, and checking that everything is running as expected.
With Security Hub, you can now use rules to automatically update various fields in findings that match defined criteria. This allows you to automatically suppress findings, update findings’ severities according to organizational policies, change findings’ workflow status, and add notes. As findings are ingested, automation rules look for findings that meet defined criteria and update the specified fields in findings that meet the criteria. For example, a user can create a rule that automatically sets the finding’s severity to “Critical” if the finding account ID is of a known business-critical account. A user could also automatically suppress findings for a specific control in an account where the finding represents an accepted risk.
With automation rules, Security Hub provides you a simplified way to build automations directly from the Security Hub console and API. This reduces repetitive work for cloud security and DevOps engineers and can reduce the mean time to response.
In this section, we’ve put together some examples of how Security Hub automation rules can help you. There’s a lot of flexibility in how you can use the rules, and we expect there will be many variations that your organization will use when contextual information about security risk has been added.
Security Hub offers protection by using hundreds of security controls that create findings that have a severity associated with them. Sometimes, you might want to elevate that severity according to your organizational policies or according to the context of the finding, such as the account it relates to. With automation rules, you can now automatically elevate the severity for specific controls when they are in a specific account.
For example, the AWS Foundational Security Best Practices control GuardDuty.1 has a “High” severity by default. But you might consider such a finding to have “Critical” severity if it occurs in one of your top production accounts. To change the severity automatically, you can choose GeneratorId as a criteria and check that it’s equal to aws-foundational-security-best-practices/v/1.0.0/GuardDuty.1, and also add AwsAccountId as a criteria and check that it’s equal to YOUR_ACCOUNT_IDs. Then, add an action to update the severity to “Critical,” and add a note to the person who will look at the finding that reads “Urgent — look into these production accounts.”
You can set up this automation rule through the AWS CLI, the console, the Security Hub API, or the AWS SDK for Python (Boto3), as follows.
aws securityhub create-automation-rule \—rule-name "Elevate severity for findings in production accounts - GuardDuty.1" \—rule-status "ENABLED"" \—rule-order 1 \—description "Elevate severity for findings in production accounts - GuardDuty.1" \—criteria '{"GeneratorId": [{"Value": "aws-foundational-security-best-practices/v/1.0.0/GuardDuty.1","Comparison": "EQUALS"}, "AwsAccountId": [{"Value": "<111122223333>","Comparison": "EQUALS"},]}' \—actions '[{"Type": "FINDING_FIELDS_UPDATE","FindingFieldsUpdate": {"Severity": {"Label": "CRITICAL"},"Note": {"Text": "Urgent – look into these production accounts","UpdatedBy": "sechub-automation"}}}]' \—region us-east-1

Figure 1: Automation rules in the Security Hub console

Figure 2: Create a new custom rule

Figure 3: Information added for the rule criteria

Figure 4: Preview section

Figure 5: Automated action to be taken against the findings that match the criteria

Figure 6: Set the rule status to Enabled

Figure 7: Newly created rule within the Security Hub Automations page
Note: In figure 7, you can see multiple automation rules. When you create automation rules, you assign each rule an order number. This determines the order in which Security Hub applies your automation rules. This becomes important when multiple rules apply to the same finding or finding field. When multiple rule actions apply to the same finding field, the rule with the highest numerical value for rule order is applied last and has the ultimate effect on that field.
Additionally, if your preferred deployment method is to use the API or AWS SDK for Python (Boto3), we have information on how you can use these means of deployment in our public documentation.
Imagine a situation where you have findings associated to a wide range of resources. Typically, organizations will attempt to prioritize which findings to remediate first. You can achieve this prioritization through Security Hub and the contextual fields that are available for you to use — for example, by using the severity of the finding or the account ID the resource is sitting in. You might also have your own prioritization based on other factors. You could add this additional context to findings by using a tagging strategy. With automation rules, you can now automatically elevate the severity for specific findings based on the tag value associated to the resource.
For example, if a finding comes into Security Hub with the severity rating “Medium,” but the resource in question is critical to the business and has the tag production associated to it, you could automatically raise the severity rating to “High.”
Note: This will work only for findings where there is a resource tag associated with the finding.
GuardDuty provides an overarching view of the state of threats to deployed resources in your organization’s cloud environment. After evaluation, GuardDuty produces findings related to these threats. The findings produced by GuardDuty have different severities, to help organizations with prioritization. Some of these findings will be given an “Informational” severity. “Informational” indicates that no issue was found and the content of the finding is purely to give information. After you have evaluated the context of the finding, you might want to suppress any additional findings that match the same criteria.
For example, you might want to set up a rule so that new findings with the generator ID that produced “Informational” findings are suppressed, keeping only the findings that need action.
When you create a new rule, you can also choose to create a rule from a template. These templates are regularly updated with use cases that are applicable for many customers.

Figure 8: Select an automation rule template
For organizations that operate in multiple AWS Regions, we’ve provided a solution that you can use to replicate rules created in your central Security Hub admin account into these additional Regions. You can find the sample code for this solution in our GitHub repo.
In this blog post, we’ve discussed the importance of automation and its ability to help organizations scale operations within the cloud. We’ve introduced a new capability in AWS Security Hub, automation rules, that can help reduce the repetitive tasks your operational teams may be facing, and we’ve showcased some example use cases to get you started. Start using automation rules in your environment today. We’re excited to see what use cases you will solve with this feature and as always, are happy to receive any feedback.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/migrating-critical-traffic-at-scale-with-no-downtime-part-2-4b1c8c7155c1
Shyam Gala, Javier Fernandez-Ivern, Anup Rokkam Pratap, Devang Shah
Picture yourself enthralled by the latest episode of your beloved Netflix series, delighting in an uninterrupted, high-definition streaming experience. Behind these perfect moments of entertainment is a complex mechanism, with numerous gears and cogs working in harmony. But what happens when this machinery needs a transformation? This is where large-scale system migrations come into play. Our previous blog post presented replay traffic testing — a crucial instrument in our toolkit that allows us to implement these transformations with precision and reliability.
Replay traffic testing gives us the initial foundation of validation, but as our migration process unfolds, we are met with the need for a carefully controlled migration process. A process that doesn’t just minimize risk, but also facilitates a continuous evaluation of the rollout’s impact. This blog post will delve into the techniques leveraged at Netflix to introduce these changes to production.
Canary deployments are an effective mechanism for validating changes to a production backend service in a controlled and limited manner, thus mitigating the risk of unforeseen consequences that may arise due to the change. This process involves creating two new clusters for the updated service; a baseline cluster containing the current version running in production and a canary cluster containing the new version of the service. A small percentage of production traffic is redirected to the two new clusters, allowing us to monitor the new version’s performance and compare it against the current version. By collecting and analyzing key performance metrics of the service over time, we can assess the impact of the new changes and determine if they meet the availability, latency, and performance requirements.
Some product features require a lifecycle of requests between the customer device and a set of backend services to drive the feature. For instance, video playback functionality on Netflix involves requesting URLs for the streams from a service, calling the CDN to download the bits from the streams, requesting a license to decrypt the streams from a separate service, and sending telemetry indicating the successful start of playback to yet another service. By tracking metrics only at the level of service being updated, we might miss capturing deviations in broader end-to-end system functionality.
Sticky Canary is an improvement to the traditional canary process that addresses this limitation. In this variation, the canary framework creates a pool of unique customer devices and then routes traffic for this pool consistently to the canary and baseline clusters for the duration of the experiment. Apart from measuring service-level metrics, the canary framework is able to keep track of broader system operational and customer metrics across the canary pool and thereby detect regressions on the entire request lifecycle flow.
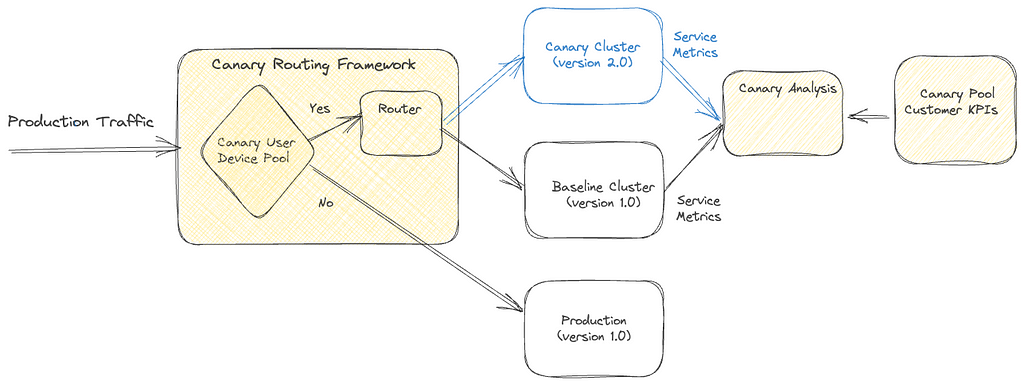
It is important to note that with sticky canaries, devices in the canary pool continue to be routed to the canary throughout the experiment, potentially resulting in undesirable behavior persisting through retries on customer devices. Therefore, the canary framework is designed to monitor operational and customer KPI metrics to detect persistent deviations and terminate the canary experiment if necessary.
Canaries and sticky canaries are valuable tools in the system migration process. Compared to replay testing, canaries allow us to extend the validation scope beyond the service level. They enable verification of the broader end-to-end system functionality across the request lifecycle for that functionality, giving us confidence that the migration will not cause any disruptions to the customer experience. Canaries also provide an opportunity to measure system performance under different load conditions, allowing us to identify and resolve any performance bottlenecks. They enable us to further fine-tune and configure the system, ensuring the new changes are integrated smoothly and seamlessly.
A/B testing is a widely recognized method for verifying hypotheses through a controlled experiment. It involves dividing a portion of the population into two or more groups, each receiving a different treatment. The results are then evaluated using specific metrics to determine whether the hypothesis is valid. The industry frequently employs the technique to assess hypotheses related to product evolution and user interaction. It is also widely utilized at Netflix to test changes to product behavior and customer experience.
A/B testing is also a valuable tool for assessing significant changes to backend systems. We can determine A/B test membership in either device application or backend code and selectively invoke new code paths and services. Within the context of migrations, A/B testing enables us to limit exposure to the migrated system by enabling the new path for a smaller percentage of the member base. Thereby controlling the risk of unexpected behavior resulting from the new changes. A/B testing is also a key technique in migrations where the updates to the architecture involve changing device contracts as well.
Canary experiments are typically conducted over periods ranging from hours to days. However, in certain instances, migration-related experiments may be required to span weeks or months to obtain a more accurate understanding of the impact on specific Quality of Experience (QoE) metrics. Additionally, in-depth analyses of particular business Key Performance Indicators (KPIs) may require longer experiments. For instance, envision a migration scenario where we enhance the playback quality, anticipating that this improvement will lead to more customers engaging with the play button. Assessing relevant metrics across a considerable sample size is crucial for obtaining a reliable and confident evaluation of the hypothesis. A/B frameworks work as effective tools to accommodate this next step in the confidence-building process.
In addition to supporting extended durations, A/B testing frameworks offer other supplementary capabilities. This approach enables test allocation restrictions based on factors such as geography, device platforms, and device versions, while also allowing for analysis of migration metrics across similar dimensions. This ensures that the changes do not disproportionately impact specific customer segments. A/B testing also provides adaptability, permitting adjustments to allocation size throughout the experiment.
We might not use A/B testing for every backend migration. Instead, we use it for migrations in which changes are expected to impact device QoE or business KPIs significantly. For example, as discussed earlier, if the planned changes are expected to improve client QoE metrics, we would test the hypothesis via A/B testing.
After completing the various stages of validation, such as replay testing, sticky canaries, and A/B tests, we can confidently assert that the planned changes will not significantly impact SLAs (service-level-agreement), device level QoE, or business KPIs. However, it is imperative that the final rollout is regulated to ensure that any unnoticed and unexpected problems do not disrupt the customer experience. To this end, we have implemented traffic dialing as the last step in mitigating the risk associated with enabling the changes in production.
A dial is a software construct that enables the controlled flow of traffic within a system. This construct samples inbound requests using a distribution function and determines whether they should be routed to the new path or kept on the existing path. The decision-making process involves assessing whether the distribution function’s output aligns within the range of the predefined target percentage. The sampling is done consistently using a fixed parameter associated with the request. The target percentage is controlled via a globally scoped dynamic property that can be updated in real-time. By increasing or decreasing the target percentage, traffic flow to the new path can be regulated instantaneously.
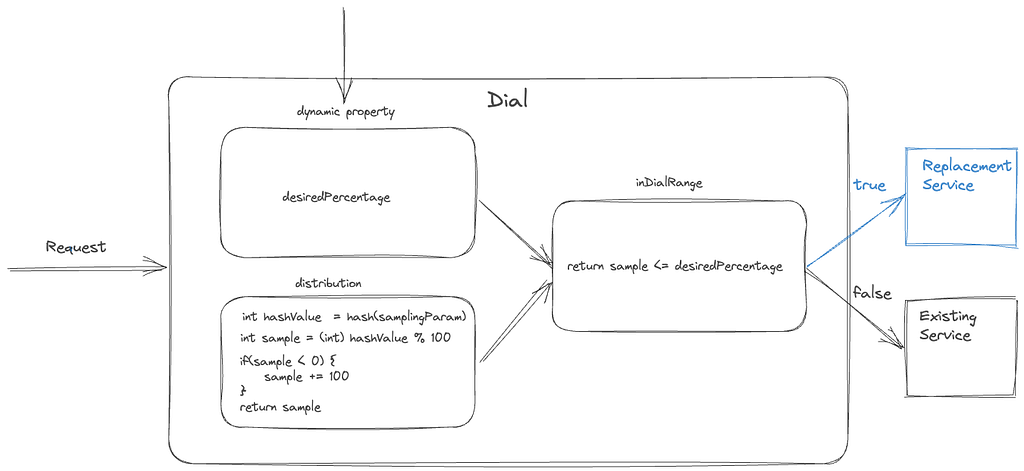
The selection of the actual sampling parameter depends on the specific migration requirements. A dial can be used to randomly sample all requests, which is achieved by selecting a variable parameter like a timestamp or a random number. Alternatively, in scenarios where the system path must remain constant with respect to customer devices, a constant device attribute such as deviceId is selected as the sampling parameter. Dials can be applied in several places, such as device application code, the relevant server component, or even at the API gateway for edge API systems, making them a versatile tool for managing migrations in complex systems.
Traffic is dialed over to the new system in measured discrete steps. At every step, relevant stakeholders are informed, and key metrics are monitored, including service, device, operational, and business metrics. If we discover an unexpected issue or notice metrics trending in an undesired direction during the migration, the dial gives us the capability to quickly roll back the traffic to the old path and address the issue.
The dialing steps can also be scoped at the data center level if traffic is served from multiple data centers. We can start by dialing traffic in a single data center to allow for an easier side-by-side comparison of key metrics across data centers, thereby making it easier to observe any deviations in the metrics. The duration of how long we run the actual discrete dialing steps can also be adjusted. Running the dialing steps for longer periods increases the probability of surfacing issues that may only affect a small group of members or devices and might have been too low to capture and perform shadow traffic analysis. We can complete the final step of migrating all the production traffic to the new system using the combination of gradual step-wise dialing and monitoring.
Stateful APIs pose unique challenges that require different strategies. While the replay testing technique discussed in the previous part of this blog series can be employed, additional measures outlined earlier are necessary.
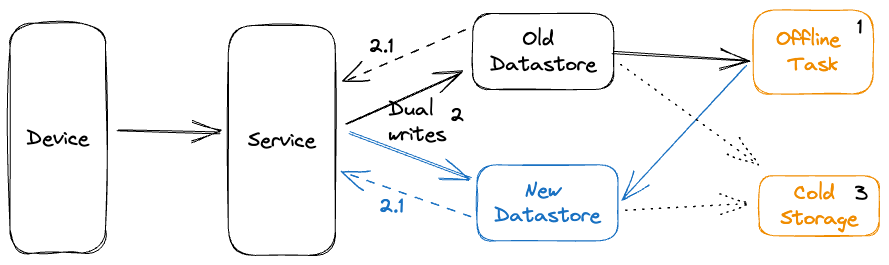
This alternate migration strategy has proven effective for our systems that meet certain criteria. Specifically, our data model is simple, self-contained, and immutable, with no relational aspects. Our system doesn’t require strict consistency guarantees and does not use database transactions. We adopt an ETL-based dual-write strategy that roughly follows this sequence of steps:
Clean-up of any migration-related code and configuration after the migration is crucial to ensure the system runs smoothly and efficiently and we don’t build up tech debt and complexity. Once the migration is complete and validated, all migration-related code, such as traffic dials, A/B tests, and replay traffic integrations, can be safely removed from the system. This includes cleaning up configuration changes, reverting to the original settings, and disabling any temporary components added during the migration. In addition, it is important to document the entire migration process and keep records of any issues encountered and their resolution. By performing a thorough clean-up and documentation process, future migrations can be executed more efficiently and effectively, building on the lessons learned from the previous migrations.
We have utilized a range of techniques outlined in our blog posts to conduct numerous large, medium, and small-scale migrations on the Netflix platform. Our efforts have been largely successful, with minimal to no downtime or significant issues encountered. Throughout the process, we have gained valuable insights and refined our techniques. It should be noted that not all of the techniques presented are universally applicable, as each migration presents its own unique set of circumstances. Determining the appropriate level of validation, testing, and risk mitigation requires careful consideration of several factors, including the nature of the changes, potential impacts on customer experience, engineering effort, and product priorities. Ultimately, we aim to achieve seamless migrations without disruptions or downtime.
In a series of forthcoming blog posts, we will explore a selection of specific use cases where the techniques highlighted in this blog series were utilized effectively. They will focus on a comprehensive analysis of the Ads Tier Launch and an extensive GraphQL migration for various product APIs. These posts will offer readers invaluable insights into the practical application of these methodologies in real-world situations.

Migrating Critical Traffic At Scale with No Downtime — Part 2 was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/new-amazon-s3-dual-layer-server-side-encryption-with-keys-stored-in-aws-key-management-service-dsse-kms/
Today, we are launching Amazon S3 dual-layer server-side encryption with keys stored in AWS Key Management Service (DSSE-KMS), a new encryption option in Amazon S3 that applies two layers of encryption to objects when they are uploaded to an Amazon Simple Storage Service (Amazon S3) bucket. DSSE-KMS is designed to meet National Security Agency CNSSP 15 for FIPS compliance and Data-at-Rest Capability Package (DAR CP) Version 5.0 guidance for two layers of CNSA encryption. Using DSSE-KMS, you can fulfill regulatory requirements to apply multiple layers of encryption to your data.
Amazon S3 is the only cloud object storage service where customers can apply two layers of encryption at the object level and control the data keys used for both layers. DSSE-KMS makes it easier for highly regulated customers to fulfill rigorous security standards, such as US Department of Defense (DoD) customers.
With DSSE-KMS, you can specify dual-layer server-side encryption (DSSE) in the PUT or COPY request for an object or configure your S3 bucket to apply DSSE to all new objects by default. You can also enforce DSSE-KMS using IAM and bucket policies. Each layer of encryption uses a separate cryptographic implementation library with individual data encryption keys. DSSE-KMS helps protect sensitive data against the low probability of a vulnerability in a single layer of cryptographic implementation.
DSSE-KMS simplifies the process of applying two layers of encryption to your data, without having to invest in infrastructure required for client-side encryption. Each layer of encryption uses a different implementation of the 256-bit Advanced Encryption Standard with Galois Counter Mode (AES-GCM) algorithm. DSSE-KMS uses the AWS Key Management Service (AWS KMS) to generate data keys, allowing you to control your customer managed keys by setting permissions per key and specifying key rotation schedules. With DSSE-KMS, you can now query and analyze your dual-encrypted data with AWS services such as Amazon Athena, Amazon SageMaker, and more.
With this launch, Amazon S3 now offers four options for server-side encryption:
Let’s see how DSSE-KMS works in practice.
Create an S3 Bucket and Turn on DSSE-KMS
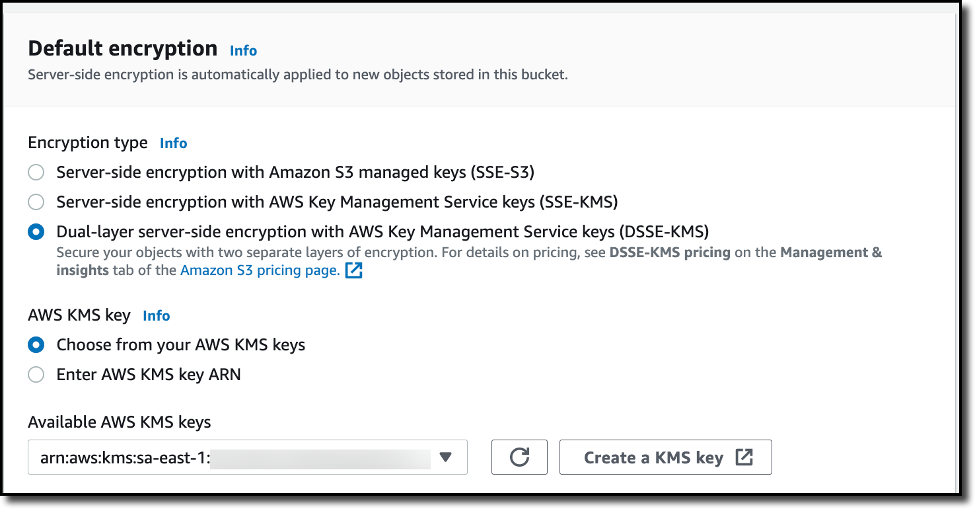
To create a new bucket in the Amazon S3 console, I choose Buckets in the navigation pane. I choose Create bucket, and I select a unique and meaningful name for the bucket. Under Default encryption section, I choose DSSE-KMS as the encryption option. From the available AWS KMS keys, I select a key for my requirements. Finally, I choose Create bucket to complete the creation of the S3 bucket, encrypted by DSSE-KMS encryption settings.
Upload an Object to the DSSE-SSE enabled S3 Bucket
In the Buckets list, I choose the name of the bucket that I want to upload an object to. On the Objects tab for the bucket, I choose Upload. Under Files and folders, I choose Add files. I then choose a file to upload, and then choose Open. Under Server-side encryption, I choose Do not specify an encryption key. I then choose Upload.

Once the object is uploaded to the S3 bucket, I notice that the uploaded object inherits the Server-side encryption settings from the bucket.

Download a DSSE-KMS Encrypted Object from an S3 Bucket
I select the object that I previously uploaded and choose Download or choose Download as from the Object actions menu. Once the object is downloaded, I open it locally, and the object is decrypted automatically, requiring no change to client applications.
Now Available
Amazon S3 dual-layer server-side encryption with keys stored in AWS KMS (DSSE-KMS) is available today in all AWS Regions. You can get started with DSSE-KMS via the AWS CLI or AWS Management Console. To learn more about all available encryption options on Amazon S3, visit the Amazon S3 User Guide. For pricing information on DSSE-KMS, visit the Amazon S3 pricing page (Storage tab) and the AWS KMS pricing page.
— Irshad
Post Syndicated from Nir Tsruya original https://aws.amazon.com/blogs/big-data/how-klarna-bank-ab-built-real-time-decision-making-with-amazon-kinesis-data-analytics-for-apache-flink/
This is a joint post co-authored with Nir Tsruya from Klarna Bank AB.
Klarna is a leading global payments and shopping service, providing smarter and more flexible shopping and purchase experiences to 150 million active consumers across more than 500,000 merchants in 45 countries. Klarna offers direct payments, pay after delivery options, and instalment plans in a smooth one-click purchase experience that lets consumers pay when and how they prefer to. The ability to utilize data to make near-real-time decisions is a source of competitive advantage for Klarna.
This post presents a reference architecture for real-time queries and decision-making on AWS using Amazon Kinesis Data Analytics for Apache Flink. In addition, we explain why the Klarna Decision Tooling team selected Kinesis Data Analytics for Apache Flink for their first real-time decision query service. We show how Klarna uses Kinesis Data Analytics for Apache Flink as part of an end-to-end solution including Amazon DynamoDB and Apache Kafka to process real-time decision-making.
AWS offers a rich set of services that you can use to realize real-time insights. These services include Kinesis Data Analytics for Apache Flink, the solution Klarna that uses to underpin automated decision-making in their business today. Kinesis Data Analytics for Apache Flink allows you to easily build stream processing applications for a variety of sources including Amazon Kinesis Data Streams, Amazon Managed Streaming for Apache Kafka (Amazon MSK), and Amazon MQ.
Klarna’s customers expect a real-time, frictionless, online experience when shopping and paying online. In the background, Klarna needs to assess risks such as credit risk, fraud attempts, and money laundering for every customer credit request in every operating geography. The outcome of this risk assessment is called a decision. Decisions generate millions of risk assessment transactions a day that must be run in near-real time. The final decision is the record of whether Klarna has approved or rejected the request to extend credit to a consumer. These underwriting decisions are critical artefacts. First, they contain information that must be persisted for legal reasons. Second, they are used to build profiles and models that are fed into underwriting policies to improve the decision process. Under the hood, a decision is the sum of a number of transactions (for example, credit checks), coordinated and persisted via a decision store.
Klarna wanted to build a framework to ensure decisions persist successfully, ensuring timely risk assessment and quick decisions for customers. First, the Klarna team looked to solve the problem of producing and capturing decisions by using a combination of Apache Kafka and AWS Lambda. By publishing decision artefacts directly to a Kafka topic, the Klarna team found that high latency could cause long transaction wait times or transactions to be rejected altogether, leading to delays in getting ratified decisions to customers in a timely fashion and potential lost revenue. This approach also caused operational overhead for the Klarna team, including management of the schema evolution, replaying old events, and native integration of Lambda with their self-managed Apache Kafka clusters.
Klarna was able to set out their requirements for a solution to capture risk assessment artefacts (decisions), acting as a source of truth for all underwriting decisions within Klarna. The key requirements included at-least once reliability and millisecond latency, enabling real-time access to decision-making and the ability to replay past events in case of missing data in downstream systems. Additionally, the team needed a system that could scale to keep pace with Klarna’s rapid [10 times] growth.
The solution consists of two components: a combination of an highly available API with DynamoDB as the data store to store each decision, and Amazon DynamoDB Streams with Kinesis Data Analytics. Kinesis Data Analytics is a fully managed Apache Flink service and used to stream, process, enrich, and standardize the decision in real time and replay past events (if needed).
The following diagram illustrates the overall flow from end-user to the downstream systems.
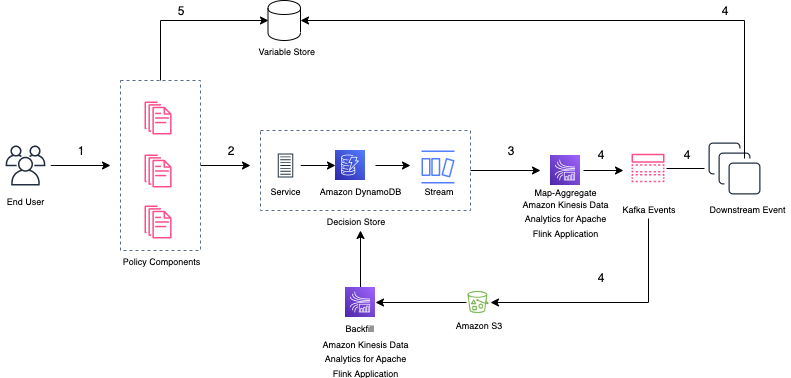
The flow includes the following steps:
The decision store provides a standardized workflow for processing and producing events for downstream systems and customer support. With all the events captured and safely stored in DynamoDB, the decision store provides an API for support engineers (and other supporting tools like chatbots) to query and access past decisions in near-real time.
The solution provided benefits in three areas.
First, the managed nature of Kinesis Data Analytics allowed the Klarna team to focus on value-adding application development instead of managing infrastructure. The team is able to onboard new use cases in less than a week. They can take full advantage of the auto scaling feature in Kinesis Data Analytics and pre-built sources and destinations.
Second, the team can use Apache Flink to ensure the accuracy, completeness, consistency, and reliability of data. Flink’s native capability of stateful computation and data accuracy through the use of checkpoints and savepoints directly supports Klarna team’s vision to add more logic into the pipelines, allowing the team to expand to different use cases confidently. Additionally, the low latency of the service ensures that enriched decision artefacts are available to consumers and subsequently to the policy agents for future decision-making in near-real time.
Third, the solution enables the Klarna team to take advantage of the Apache Flink open-source community, which provides rich community support and the opportunity to contribute back to the community by bug fixing or adding new features.
This solution has proven to scale with increased adoption of a new use case, translating to a 10-times increase in events over 3 months.
The Klarna team faced a few challenges with Flink serialization and upgrading Apache Flink versions. Flink serialization is an interesting concept and critical for the application’s performance. Flink uses a different set of serializers in order to serialize data between the operators. It’s up to the team to configure the best and most efficient serializer based on the use case. The Klarna team configured the objects as Flink POJO, which reduced the pipeline runtime by 85%. For more information, refer to Flink Serialization Tuning Vol. 1: Choosing your Serializer — if you can before deploying a Flink application to production.
The other challenge faced by the team was upgrading the Apache Flink version in Kinesis Data Analytics. Presently, the Kinesis Data Analytics for Apache Flink application requires the creation of a new Kinesis Data Analytics for Apache Flink application. Currently, reusing a snapshot (the binary artefact representing the state of the Flink application, used to restore the application to the last checkpoint taken) is not possible between two different applications. For that reason, upgrading the Apache Flink version requires additional steps in order to ensure the application doesn’t lose data.
The team is looking into expanding the usage of Kinesis Data Analytics and Flink in Klarna. Because the team is already highly experienced in the technology, their first ambition will be to own the infrastructure of a Kinesis Data Analytics for Apache Flink deployment, and connect it to different Klarna data sources. The team then will host business logic provided by other departments in Klarna such as Fraud Prevention. This will allow the specialised teams to concentrate on the business logic and fraud detection algorithms, while decision tooling will handle the infrastructure.
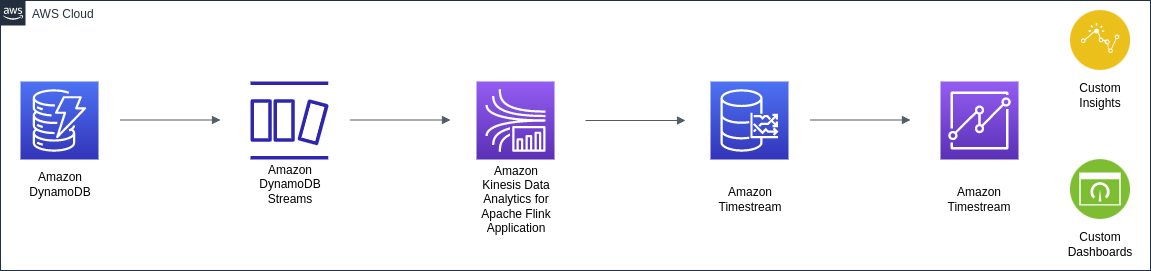
A key part of choosing Kinesis Data Analytics for Apache Flink was the open-source community and support.
Several teams within Klarna created different implementations of a Flink DynamoDB connector, which were used internally by multiple teams. Klarna then identified the opportunity to create a single maintained DynamoDB Flink connector and contribute it to the open-source community. This has initiated a collaboration within Klarna, led by the Klarna Flink experts and accompanied by Flink open-source contributors from AWS.
The main principle for designing the DynamoDB Flink connector was utilizing the different write capacity modes of DynamoDB. DynamoDB supports On-demand and Provisioned capacity modes and each behaves differently when it comes to how it handles incoming throughput. On-demand mode will automatically scale up DynamoDB write capacity and apply itself to the incoming load. However, Provisioned mode is more limiting, and will throttle incoming traffic according to the provisioned write capacity.
To comply with this process, the DynamoDB Flink connector was designed to allow concurrent writes to DynamoDB. The number of concurrent requests can be configured to comply with DynamoDB’s capacity mode. In addition, the DynamoDB Flink connector supports backpressure handling in case the DynamoDB write provisioning is low compared to the incoming load from the Apache Flink application.
At the time of writing, the DynamoDB Flink connector has been open sourced.
Klarna has successfully been running Kinesis Data Analytics for Apache Flink in production since October 2020. It provides several key benefits. The Klarna development team can focus on development, not on cluster and operational management. Their applications can be quickly modified and uploaded. The low latency properties of the service ensure a near-real-time experience for end-users, data consumers, and producers, which underpin risk assessment and the decision-making processes underpinning continuous traffic growth. At the same time, exactly-once processing in combination with Flink checkpoints and savepoints means that critical decision-making and legal data is not lost.
To learn more about Kinesis Data Analytics and getting started, refer to Using a Studio notebook with Kinesis Data Analytics for Apache Flink and More Kinesis Data Analytics Solutions on GitHub.
 Nir Tsruya is a Lead Engineer in Klarna. He leads 2 engineering teams focusing mainly on real time data processing and analytics at large scale.
 Ankit Gupta is a Senior Solutions Architect at Amazon Web Serves based in Stockholm, Sweden, where we helps customers across the Nordics succeed in Cloud. He’s particularly passionate about building strong Networking foundation in Cloud.
 Daniel Arenhage is a Solutions Architect at Amazon Web Services based in Gothenburg, Sweden.
Post Syndicated from Ayah Chamseddin original https://aws.amazon.com/blogs/big-data/federate-amazon-quicksight-access-with-open-source-identity-provider-keycloak/
Amazon QuickSight is a scalable, serverless, embeddable, machine learning (ML) powered business intelligence (BI) service built for the cloud that supports identity federation in both Standard and Enterprise editions. Organizations are working toward centralizing their identity and access strategy across all their applications, including on-premises and third-party. Many organizations use Keycloak as their identity provider (IdP) to control and manage user authentication and authorization centrally. You can enable role-based access control to make sure users get appropriate role permissions in QuickSight based on their entitlement stored in Keycloak attributes.
In this post, we walk through the steps you need to configure federated single sign-on (SSO) between QuickSight and open-source IdP Keycloak. We also demonstrate ways to to assign QuickSight roles based on Keycloak membership. Administrators can publish QuickSight applications on the Keycloak Admin console. This enables you to SSO to QuickSight using your Keycloak credentials.
To complete the walkthrough, you need the following prerequisites:
The walkthrough includes the following steps:
To configure the integration of an SSO application in Keycloak, you need to create a Keycloak client application.

aws-realm.

Follow the steps to configure the application in Keycloak.


/realms/aws-client/protocol/saml/clients/amazon-qs.amazon-qs.https://quicksight.aws.amazon.com.


https://<your_host_domain>/realms/aws-realm/protocol/saml/descriptor.
You now have Keycloak installed in your local machine, a new client added, AWS federation properties updated, and the Keycloak SAML metadata downloaded for AWS use in the following section.
To configure Keycloak as your SAML IdP, complete the following steps:

keycloak.
The ARN is used in a later step for federated users and IdP Keycloak advanced configuration.

Create three IAM policies for mapping to three different roles with permissions in QuickSight (admin, author, and reader):
Use the following steps to setup the QuickSight-Admin policy. This policy grants the admin privileges in QuickSight to the federated user.

QuickSight-Admin.
| Policy Name | JSON Text |
QuickSight-Admin |
|
QuickSight-Author |
|
QuickSight-Reader |
QuickSight-Admin.
QuickSight-Reader and QuickSight-Author.


Create the roles that your Keycloak users assume when federating into QuickSight. Use the following steps to set up the admin role:
keycloak).
QuickSight-Admin IAM policy you created in the previous step.QuickSight-Admin-Role.
QuickSight-Author-Role, use the policy QuickSight-AuthorQuickSight-Reader-Role, use the policy QuickSight-Reader

With the completion of these steps, you have created an IdP in AWS, created policies, and created roles for the Keycloak IdP.
To create a role for the client, complete the following steps:
aws-realm and client amazon:webservices.arn:aws:iam:: <AWS account>:role/QuickSight-Admin-Role,arn:aws:iam::<AWS account>:saml-provider/keycloak
QuickSight-Author-Role and QuickSight-Reader-Role.
To create a mapper for the client, complete the following steps:
amazon:webservices for aws-realm.

https://aws.amazon.com/SAML/Attributes/Role
https://aws.amazon.com/SAML/Attributes/SessionDuration
To manually add the values needed for the Session Name mapper, provide the following information:
https://aws.amazon.com/SAML/Attributes/SessionName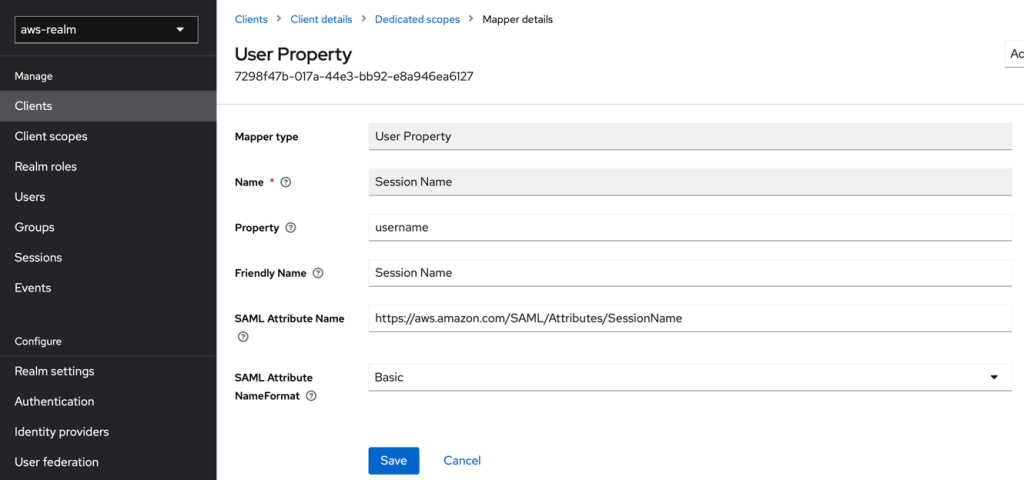
To create groups and users for the Keycloak IdP, complete the following steps:
READ_ONLY_AWS_USERS.


Complete these steps to create a sample user with credentials:


READ_ONLY_AWS_USERS.

You now have a Keycloak role for the realm and client, and Keycloak mappers, groups, and users in your groups.
Let’s invoke the application you have created to seamlessly sign in to QuickSight using the following URL. Make sure you enter your domain for Keycloak.
http://<your domain>/realms/aws-realm/protocol/saml/clients/amazon-qs
When prompted for your user ID and password, enter the credentials that you created earlier.

Keycloak successfully validates the credentials and federates access to the QuickSight console by assuming the role.

In this post, we provided step-by-step instructions to configure federated SSO between Keycloak IdP and QuickSight. We also discussed how to create new roles and map users and groups in Keycloak to IAM for secure access to QuickSight.
If you have any questions or feedback, please leave a comment.
 Ayah Chamseddin is a Sr. Engagement Manager at AWS. She has a deep understanding of cloud technologies and has successfully overseen and lead strategic projects, partnering with clients to define business objectives, develop implementation strategies, and drive the successful delivery of solutions.
 Vamsi Bhadriraju is a Data Architect at AWS. He works closely with enterprise customers to build data lakes and analytical applications on the AWS Cloud.
 Srikanth Baheti is a Specialized World Wide Principal Solutions Architect for Amazon QuickSight. He started his career as a consultant and worked for multiple private and government organizations. Later he worked for PerkinElmer Health and Sciences & eResearch Technology Inc, where he was responsible for designing and developing high traffic web applications, highly scalable and maintainable data pipelines for reporting platforms using AWS services and Serverless computing.
 Raji Sivasubramaniam is a Sr. Solutions Architect at AWS, focusing on Analytics. Raji is specialized in architecting end-to-end Enterprise Data Management, Business Intelligence and Analytics solutions for Fortune 500 and Fortune 100 companies across the globe. She has in-depth experience in integrated healthcare data and analytics with wide variety of healthcare datasets including managed market, physician targeting and patient analytics.
Post Syndicated from Amrit Singh original https://www.backblaze.com/blog/the-power-of-specialized-cloud-providers-a-game-changer-for-saas-companies/
“Nobody ever got fired for buying AWS.” It’s true: AWS’s one-size-fits-all solution worked great for most businesses, and those businesses made the shift away from the traditional model of on-prem and self-hosted servers—what we think of as Cloud 1.0—to an era where AWS was the cloud, the one and only, which is what we call Cloud 2.0. However, as the cloud landscape evolves, it’s time to question the old ways. Maybe nobody ever got fired for buying AWS, but these days, you can certainly get a lot of value (and kudos) for exploring other options.
Developers and IT teams might hesitate when it comes to moving away from AWS, but AWS comes with risks, too. If you don’t have the resources to manage and maintain your infrastructure, costs can get out of control, for one. As we enter Cloud 3.0 where the landscape is defined by the open, multi-cloud internet, there is an emerging trend that is worth considering: the rise of specialized cloud providers.
Today, I’m sharing how software as a service (SaaS) startups and modern businesses can take advantage of these highly-focused, tailored services, each specializing and excelling in specific areas like cloud storage, content delivery, cloud compute, and more. Building on a specialized stack offers more control, return on investment, and flexibility, while being able to achieve the same performance you expect from hyperscaler infrastructure.
From a cost of goods sold perspective, AWS pricing wasn’t a great fit. From an engineering perspective, we didn’t want a net-new platform. So the fact that we got both with Backblaze—a drop-in API replacement with a much better cost structure—it was just a no-brainer.
—Rory Petty, Co-Founder & CTO, Tribute
Specialized providers—including content delivery networks (CDNs) like Fastly, bunny.net, and Cloudflare, as well as cloud compute providers like Vultr—offer services that focus on a particular area of the infrastructure stack. Rather than trying to be everything to everyone, like the hyperscalers of Cloud 2.0, they do one thing and do it really well. Customers get best-of-breed services that allow them to build a tech stack tailored to their needs.
There are a number of businesses that might benefit from switching from hyperscalers to specialized cloud providers, including:
In order for businesses to take advantage of the benefits (since most applications rely on more than just one service), these services must work together seamlessly.
If you’re wondering how exactly specialized clouds can “play well with each other,” we ran a whole series of application storage webinars that talk through specific examples and uses cases. I’ll share what’s in it for you below.
Did you know a 100-millisecond delay in website load time can hurt conversion rates by 7%? In this session, Pat Patterson from Backblaze and Jim Bartos from Fastly discuss the importance of speed and latency in user experience. They highlight how Backblaze’s B2 Cloud Storage and Fastly’s content delivery network work together to deliver content quickly and efficiently across multiple regions. Businesses can ensure that their content is delivered with low latency, reducing delays and optimizing user experience regardless of the user’s location.
Delivering content to your end users at scale can be challenging and costly. Users expect exceptional web and mobile experiences with snappy load times and zero buffering. Anything less than an instantaneous response may cause them to bounce.
In this webinar, Pat Patterson demonstrates how to efficiently scale your content delivery workflows from content ingestion, transcoding, storage, to last-mile acceleration via bunny.net CDN. Pat demonstrates how to build a video hosting platform called “Cat Tube” and shows how to upload a video and play it using HTML5 video element with controls. Watch below and download the demo code to try it yourself.
With a global economic slowdown, IT and development teams are looking for ways to slash cloud budgets without compromising performance. E-commerce, SaaS platforms, and streaming applications all rely on high-performant infrastructure, but balancing bandwidth and storage costs can be challenging. In this 45-minute session, we explored how to recession-proof your growing business with key cloud optimization strategies, including ways to leverage Fastly’s CDN to balance bandwidth costs while avoiding performance tradeoffs.
Greg Hamer from Backblaze and DJ Johnson from Vultr explore the benefits of building on best-of-breed, specialized cloud stacks tailored to your business model, rather than being locked into traditional hyperscaler infrastructure. They cover real-world use cases, including:
James Ross of Nodecraft, an online gaming platform that aims to make gaming online easy, shares how he moved his global game server platform from Amazon S3 to Backblaze B2 for greater flexibility and 85% savings on storage and egress. He discusses the challenges of managing large files over the public internet, which can result in expensive bandwidth costs. By storing game titles on Backblaze B2 and delivering them through Cloudflare’s CDN, they achieve reduced latency since games are cached at the edge, and pay zero egress fees thanks to the Bandwidth Alliance. Nodecraft also benefited from Universal Data Migration, which allows customers to move large amounts of data from any cloud services or on-premises storage to Backblaze’s B2 Cloud Storage, managed by Backblaze and free of charge.
Though it may seem daunting to transition from a hyperscaler to a specialized cloud provider, it doesn’t have to be. Many specialized providers offer tools and services to make the transition as smooth as possible.
As the decision maker at your growing SaaS company, it’s worth considering whether a specialized cloud stack could be a better fit for your business. By doing so you could potentially unlock cost savings, improve performance, and gain flexibility to adapt your services to your unique needs. The one-size-fits-all is no longer the only option out there.
Take a proactive approach to cloud cost management: Get 10GB free to test and validate your proof of concept (POC) with Backblaze B2. All it takes is an email to get started.

The post The Power of Specialized Cloud Providers: A Game Changer for SaaS Companies appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.
Post Syndicated from Vinay Ujjini original https://aws.amazon.com/blogs/messaging-and-targeting/amazon-ses-set-up-notifications-for-bounces-and-complaints/
Amazon Simple Email Service (Amazon SES) is a scalable cloud email service provider that is cost-effective and flexible. Amazon SES allows businesses and individuals to send bulk emails to their customers and subscribers. However, as with any email service, there is always a risk of emails bouncing or being marked as spam by recipients. These bounces and complaints can have serious consequences for your email deliverability and can even lead to your email account being suspended or blocked. That’s why it’s important to monitor bounces and complaints when using Amazon SES for email sending. By using Simple Notification Services (Amazon SNS) notifications, you can set up notifications and proactively address any issues and ensure that your emails are delivered successfully to your intended recipients. In this blog, we’ll show how to set up notifications for bounces and complaints in Amazon SES, so you can stay on top of your email deliverability and maintain a positive sender reputation.
Understanding bounces and complaints is crucial when it comes to email marketing. In simple terms, a bounce occurs when an email is undeliverable and is returned to the sender. There are two types of bounces: soft bounces and hard bounces. A soft bounce is a temporary issue, such as a full inbox or a server error, and the email may be delivered successfully on a subsequent attempt. A hard bounce, on the other hand, is a permanent issue, such as an invalid email address, and the email will never be delivered. On the other hand, a complaint occurs when a recipient marks an email as spam or unwanted. Complaints can be particularly damaging to your email deliverability and can lead to your emails being blocked or sent to the recipient’s spam folder. By monitoring bounces and complaints and taking appropriate action, you can maintain a positive sender reputation and ensure that your emails are delivered successfully to your intended recipients.
Amazon SES provides tools like Virtual Deliverability Manager (VDM) to manage the deliverability at the ISP, sub-domain or configuration set level. You can see the details in this blog.
This post gives detailed instructions on how to use Amazon Simple Notification Service SNS to monitor and receive notifications on bounces and complaints in Amazon SES. This blog also has FAQs and troubleshooting tips if you are not receiving notifications following the setup: (below are the steps with detailed instructions and screenshots)
For this walkthrough, you should have the following prerequisites:


In this step, I am presenting two methods to monitor your bounces and complaints. Follow Demo 1, if you are looking for a simple way to monitor bounces and complaints events for a specific email identity. Follow Demo 2, if you have many email identities and you want to monitor bounces and complaints along with other events using configuration sets “groups of rules that you can apply to all your verified identities”.
Demo 1: Configure Amazon SES to monitor bounces and complaints for specific email identity (Email, Domain):
The domain/sub-domain/email identity must have a Verified status. If the identity is not in verified status, refer to steps to verify identity with Amazon SES before continuing further.
Prior to starting this demo, it is important to know if you have a verified domain, subdomain, or an email address that shares the root domain. The identity settings (such as SNS and feedback notifications) apply at the most granular level you have set up the verification. Hierarchy is as below:
Hence, if you want to monitor bounces and complaints for all email addresses under one domain, it is recommended to verify the domain identity with SES and apply this setting at the domain identity level. If you want to monitor bounces and complaints for specific email address under a verified domain identity, verify this email address explicitly with SES and apply this settings into the email identity level.


Demo 2: Configure Amazon SES to monitor bounces and complaints for emails sent with a configuration set using Amazon SES event publishing.
Configuration sets in SES are groups of rules, that you can apply to your verified identities. When you apply a configuration set to an email, all of the rules in that configuration set are applied to the email. You can use different type of rules with a configuration set. This demo will use event destination, which will allow you to publish bounces and complaints to the SNS topic.
Note: You must pass the name of the configuration set when sending an email. This can be done by either specifying the configuration set name in the headers of emails, or specifying it as a default configuration set. This can be done at the time of identity creation, or later while editing a verified identity.


Test 1: Send a test email to test Demo 1 “Configure Amazon SES to monitor bounces and complaints for specific email identity (Email, Domain) ” in previous step
In this test, I will send a test message from my verified identity which configured to send any bounce and complaint notifications it receives to SNS topic and email address subscribed to the topic. I will use SES mailbox simulator to simulate a bounce message to test this setup.


Test 2: Send a test email to test Demo 2 “Configure Amazon SES to monitor bounces and complaints for emails sent with a configuration set using Amazon SES event publishing” in previous step
In this test, you can send a test message from any verified identity and by using the configuration set created in Step 2 which is configured to send any bounce and complaint notifications to SNS topic and email address subscribed to the topic. You can use SES mailbox simulator to simulate a bounce message to test this setup.


I configured SNS topic with KMS encryption and I am not receiving bounce or complain notifications for emails:
If your Amazon SNS topic uses AWS Key Management Service (AWS KMS) for server-side encryption, you have to add permissions to the AWS KMS key policy to allow SES service access the KMS key, an example policy can be found here.
I followed Demo 2. However, when I try to send emails from any verified identity, I don’t receive bounce or complain notifications for emails:
When sending the email, make sure to select the configuration set you configured for bounce and complaints notification. If you followed demo 2 and you sent the email without explicitly using the configuration set in email headers, you will lose tracking for bounce and complaints events.
I am testing the setup. After I sent an email to the bounce simulator, I am not receiving don’t receive any bounce notification emails:
Check the SNS topic subscription if its in pending status and make sure you confirm the topic subscription via subscription email sent to you. If the topic subscription is confirmed, make sure you have access to the inbox of subscription email address and you are not applying any email filters.
You should have now successfully setup SNS notifications to monitor bounce and complaints for you Amazon SES emails. To avoid incurring any extra charges, remember to delete any resources created manually if you no longer need them for monitoring.
Resources to delete from SES console:
Resources to delete from SNS console:
Monitoring bounces and complaints is an essential part of maintaining a successful email sending system, using Amazon SES. By setting up SNS notifications for bounces and complaints, you can quickly identify any issues and take appropriate action to ensure that your emails are delivered successfully to your subscribers. By proactively managing your email deliverability, you can maintain a positive sender reputation and avoid any negative impact on your email marketing efforts.

Alaa Hammad is a Senior Cloud Support Engineer at AWS and subject matter expert in Amazon Simple Email Service and AWS Backup service. She has a 10 years of diverse experience in supporting enterprise customers across different industries. She enjoys cooking and try new recipes from different cuisines.
Vinay Ujjini is an Amazon Pinpoint and Amazon Simple Email Service Worldwide Principal Specialist Solutions Architect at AWS. He has been solving customer’s omni-channel challenges for over 15 years. He is an avid sports enthusiast and in his spare time, enjoys playing tennis & cricket.