Extend your data perimeter to the AWS Management Console with Private Access

Post Syndicated from Madhur Kulkarni original https://aws.amazon.com/blogs/security/extend-your-data-perimeter-to-the-aws-management-console-with-private-access/

Organizations in regulated industries such as financial services, government, defense, and healthcare restrict their sensitive workloads to isolated network environments with no access to the public internet. Until now, customers could restrict AWS Management Console access to authorized AWS accounts and corporate networks, but the console itself required internet connectivity. This was creating tension between operational convenience and network security controls.

We’re happy to announce that AWS Management Console Private Access is now generally available with support for virtual private clouds (VPCs) without internet connectivity. Organizations in regulated industries that restrict workloads to isolated network environments can now route all traffic for supported service consoles—including authentication flows, static assets (JavaScript, CSS, images), console-only APIs, and AWS service API calls—through AWS PrivateLink VPC endpoints, eliminating the need for an internet gateway, NAT gateway, or any route to the public internet. This capability is available in all AWS commercial Regions for a select set of supported service consoles.

In 2023, we launched AWS Management Console Private Access, which you can use to connect to the console by routing console, sign-in, and service API calls through VPC endpoints. However, accessing the console required internet connectivity for static assets and console-only APIs. This meant security teams faced a choice: allow internet connectivity to use the console or deny console access to operators working in network-isolated environments.

With this launch, AWS Management Console Private Access addresses two common scenarios:

  • Console traffic over internet restricted networks: Traffic for supported service consoles now flows entirely through your VPC endpoints—no proxy allowlists to maintain, no TLS-intercepting proxies to operate, and no CLI-only workflows to accept as a compromise. The same path works seamlessly from Amazon WorkSpacesAmazon Elastic Compute Cloud (Amazon EC2) instances, and on-premises networks connected through AWS Direct Connect or AWS Site-to-Site VPN. Combined with sign-in resource control policies (RCPs) and sign-in resource policies, you can ensure that console authentication only succeeds from expected networks—even if valid credentials are presented elsewhere, the session is denied. Teams that previously relied on restricted egress rules or manual domain allowlists now get full console access with the same network controls they already trust.
  • Data-exfiltration prevention: Private Access enables you to restrict which AWS accounts and organizational identities can use the AWS Management Console from within your VPC. This prevents access from personal accounts and from accounts outside your organization. Attach a VPC endpoint policy with an aws:ResourceOrgID condition, and console actions are automatically scoped to resources inside your organization. Sign-in RCPs add a second layer by ensuring authentication only succeeds from networks within your perimeter. Together, these controls prevent supported service consoles from being used to access resources in accounts outside your organization—such as personal accounts—without requiring complex network-layer workarounds.

In this post, you will learn how AWS Management Console Private Access works in environments without internet connectivity, and how to layer access controls using VPC endpoint policies and sign-in resource control policies (RCPs) to strengthen your data perimeter.

Solution overview

AWS Management Console Private Access and sign-in resource control policies are a natural extension of the service control policies (SCPs), resource control policies, and VPC endpoint policies you already use for API traffic; now applied to the console session itself. The same data perimeter controls for identity, resource, and network that protect your programmatic access now protect interactive browser sessions too.

Perimeter Control objective Policy construct Implementation Steps
Identity Only trusted identities can access my resources Sign-In RCPs and RBPs Restrict which principals can sign in to the console. Before authentication, signin:PrincipalArn is available for exemptions only. After authentication, RCPs restrict at the organization, account, or principal level (aws:PrincipalOrgID, aws:PrincipalAccount, aws:PrincipalArn); RBPs restrict at the account or principal level.
Identity Only trusted identities are allowed from my network Console VPC endpoint policy and Sign-In VPC endpoint policy Console endpoint: aws:PrincipalOrgID or aws:PrincipalAccount on signed-in identities. Sign-In endpoint: aws:ResourceOrgID or aws:ResourceAccount before authentication, principal and resource keys after authentication. Blocks sign-in to accounts outside your organization, such as personal accounts, from your network.
Resource My identities can access only trusted resources SCP Resource perimeter SCP with aws:ResourceOrgID follows your principals into every console session; each service API call the console makes on their behalf is denied if the target resource is outside your organization.
Resource Only trusted resources can be accessed from my network Console VPC endpoint policy and service VPC endpoint policies Console endpoint policy with aws:ResourceOrgID and aws:ResourceAccount scopes what the console can reach through your network.
Network My identities can access resources only from expected networks SCP Network perimeter SCPs that use aws:SourceVpc deny your principals’ service calls from outside expected networks. With Private Access, requests proxied by the console to supported services carry aws:SourceVpc set to the VPC hosting your Private Access endpoints. Direct browser requests carry VPC context only when the service has its own VPC endpoint, so configure endpoints for every service you use. AWS recommends conditioning on aws:SourceVpc rather than specific aws:SourceVpce values.
Network My resources can only be accessed from expected networks Sign-In RBPs and RCPs and network perimeter RCPs Sign-In policies deny console authentication from unexpected networks using aws:SourceIp, aws:SourceVpc, aws:SourceVpce, and aws:VpcSourceIp in both pre-authentication and post-authentication statements. Network perimeter RCPs apply the same network conditions to your data resources for any access path.

With this launch, Console Private Access routes browser traffic for supported service consoles through VPC endpoints, including:

  • Authentication flows – Sign-in, credential exchange, and session token requests
  • Static assets – JavaScript, CSS, and images that render the console UI
  • Service console API calls – The backend requests made when users interact with service consoles

How traffic flows from a workload in a private VPC through the three Private Access endpoints, with no path to the public internet (shown in Figure 1):

  1. The operator’s browser requests <region>.console.aws.amazon.com.
  2. The corporate DNS forwarder forwards the query to an Amazon Route 53 Resolver inbound endpoint configured within the VPC, which forwards the traffic to the console VPC endpoint.
  3. Browser traffic flows from on-premises through Direct Connect (or AWS Site-to-Site VPN) to the VPC, and the VPC endpoint routes traffic to the console service over the AWS private network.
  4. The console service redirects to the SignIn endpoint <region>.signin.aws.amazon.com to establish a browser session.
  5. The DNS now resolves to the SignIn VPC endpoint’s private IP addresses, and browser traffic flows to the SignIn service over the AWS private network.
  6. After entering credentials, the SignIn service evaluates VPC endpoint policies, in addition to resource-based policies (RBPs) and RCPs, then redirects back to the console.
  7. The console evaluates VPC endpoint policies, loads static content from the console API VPC endpoint, and enforces identity and resource restrictions when making calls to AWS service APIs.
  8. Users can now access the AWS Management Console over Private Access.
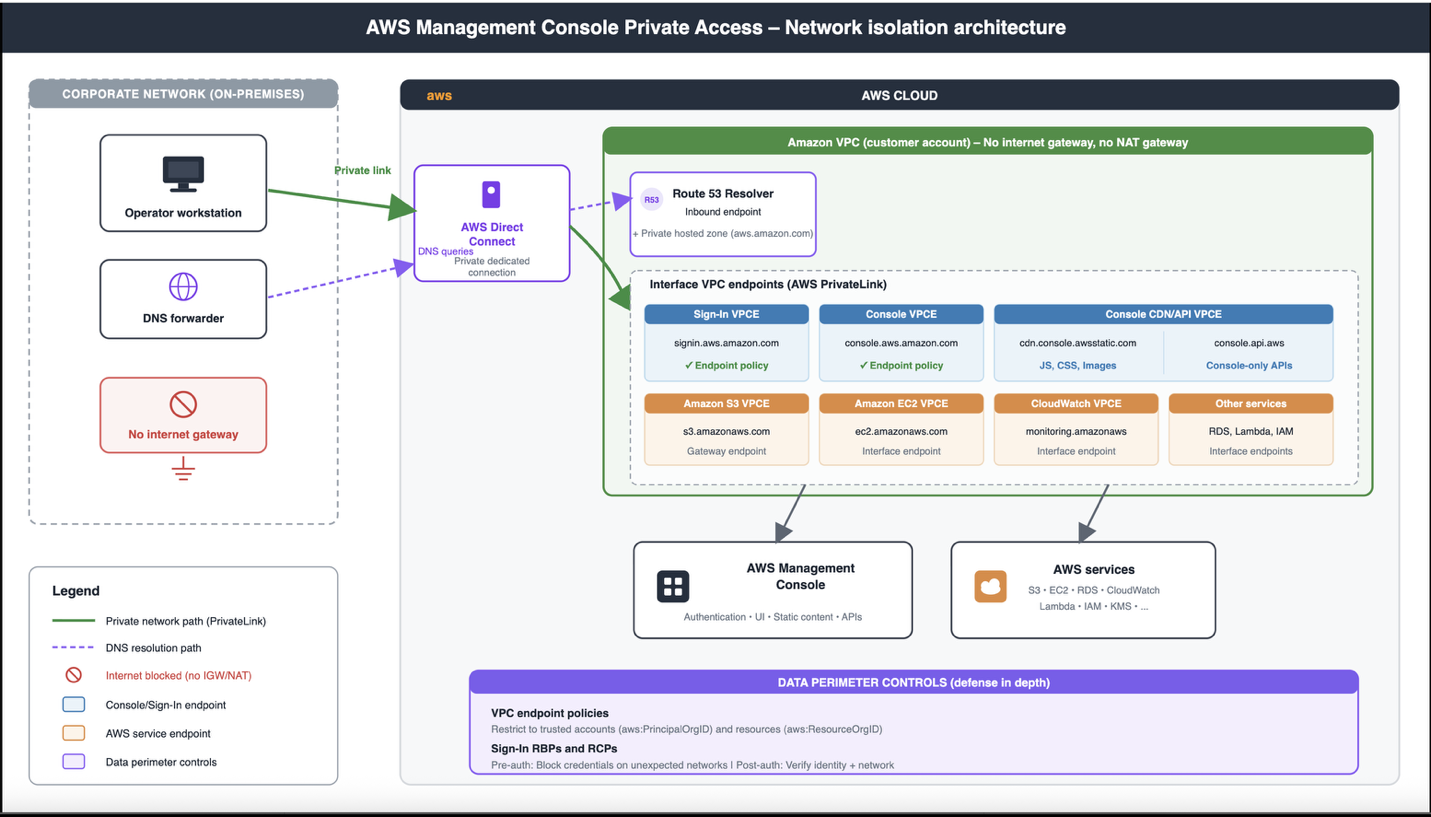
Figure 1: Network isolation architecture

Figure 1: Network isolation architecture

Deploy a pilot of AWS Management Console Private Access

This high-level walkthrough sets up AWS Management Console Private Access for a single AWS Region within one organizational unit (OU). We recommend rolling out incrementally; validate each step before you expand to additional Regions and OUs.

If you want to validate the mechanics of a Private Access deployment before you build out the full solution, the Getting started with a test environment guide walks you through a minimal configuration: a single VPC with the three Private Access endpoints and a permissive policy. This gives you a working setup to experiment with, independent of the deployment described in the rest of this post. To understand how sign-in policies can verify a user’s network location when they access the console, see Controlling console access with resource-based policies and resource control policies.

Prerequisites

You must have the following prerequisites:

Step 1: Baseline current console access

Before changing anything, use CloudTrail to map how your users access the console today. Search for eventName = ConsoleLogin over a representative window (we recommend 30 days) and review the sourceIPAddressvpcEndpointId, and awsRegion fields. Identify which identity types are in use: root userIAM user, SAML federation, and AWS IAM Identity Center. Decide which OU or account you will pilot with.

Note: A misconfigured sign-in policy can lock users out of the console. Avoid piloting in a production or shared account. Instead, use a dedicated test account and configure a break-glass principal (covered in Step 5) before enabling access enforcement.

Step 2: Create the Private Access VPC endpoints

In your chosen Region, create or identify a VPC to host the endpoints, then create three interface VPC endpoints in that VPC:

  • com.amazonaws.<region>.console for the console.
  • com.amazonaws.<region>.signin for AWS Sign-In.
  • com.amazonaws.<region>.console-static for console-only APIs. This endpoint is required only if your VPC has no internet path.

Step 3: Configure private DNS for AWS Management Console Private Access

To use AWS Management Console Private Access, you must configure private DNS so that the console domains—.console.aws.amazon.com.signin.aws.amazon.com, and the associated static-content domains—resolve to your interface endpoints’ network interfaces within your VPC.

  • For workloads inside your VPC: If the workloads in your VPC use the default Amazon Route 53 Resolver, no additional DNS configuration is required. When you create each interface endpoint, enable the private DNS name option (set PrivateDnsEnabled = true). The public console domains will then resolve automatically to the endpoint network interfaces inside your VPC. If you use a custom DNS resolver or a private hosted zone, you must configure it explicitly to map the console domains to the endpoint addresses. See Working with private hosted zones for more information. For the complete list of domains and detailed DNS configuration steps, see the AWS Management Console Private Access required endpoints documentation.
  • For workloads outside your VPC: For workloads that reach the endpoints from outside the VPC—such as corporate offices connecting over AWS Direct Connect or AWS Site-to-Site VPN—ensure that your corporate DNS resolver returns the endpoint addresses for these domains. See Simplify DNS management in a multi-account environment with Route 53 Resolver for more information.

Step 4: Verify private connectivity

Sign in to the console from a workload inside your VPC. The console should load normally. To confirm that traffic is routing through your VPC endpoints, look for the lock icon in the console navigation bar, shown in Figure 2.
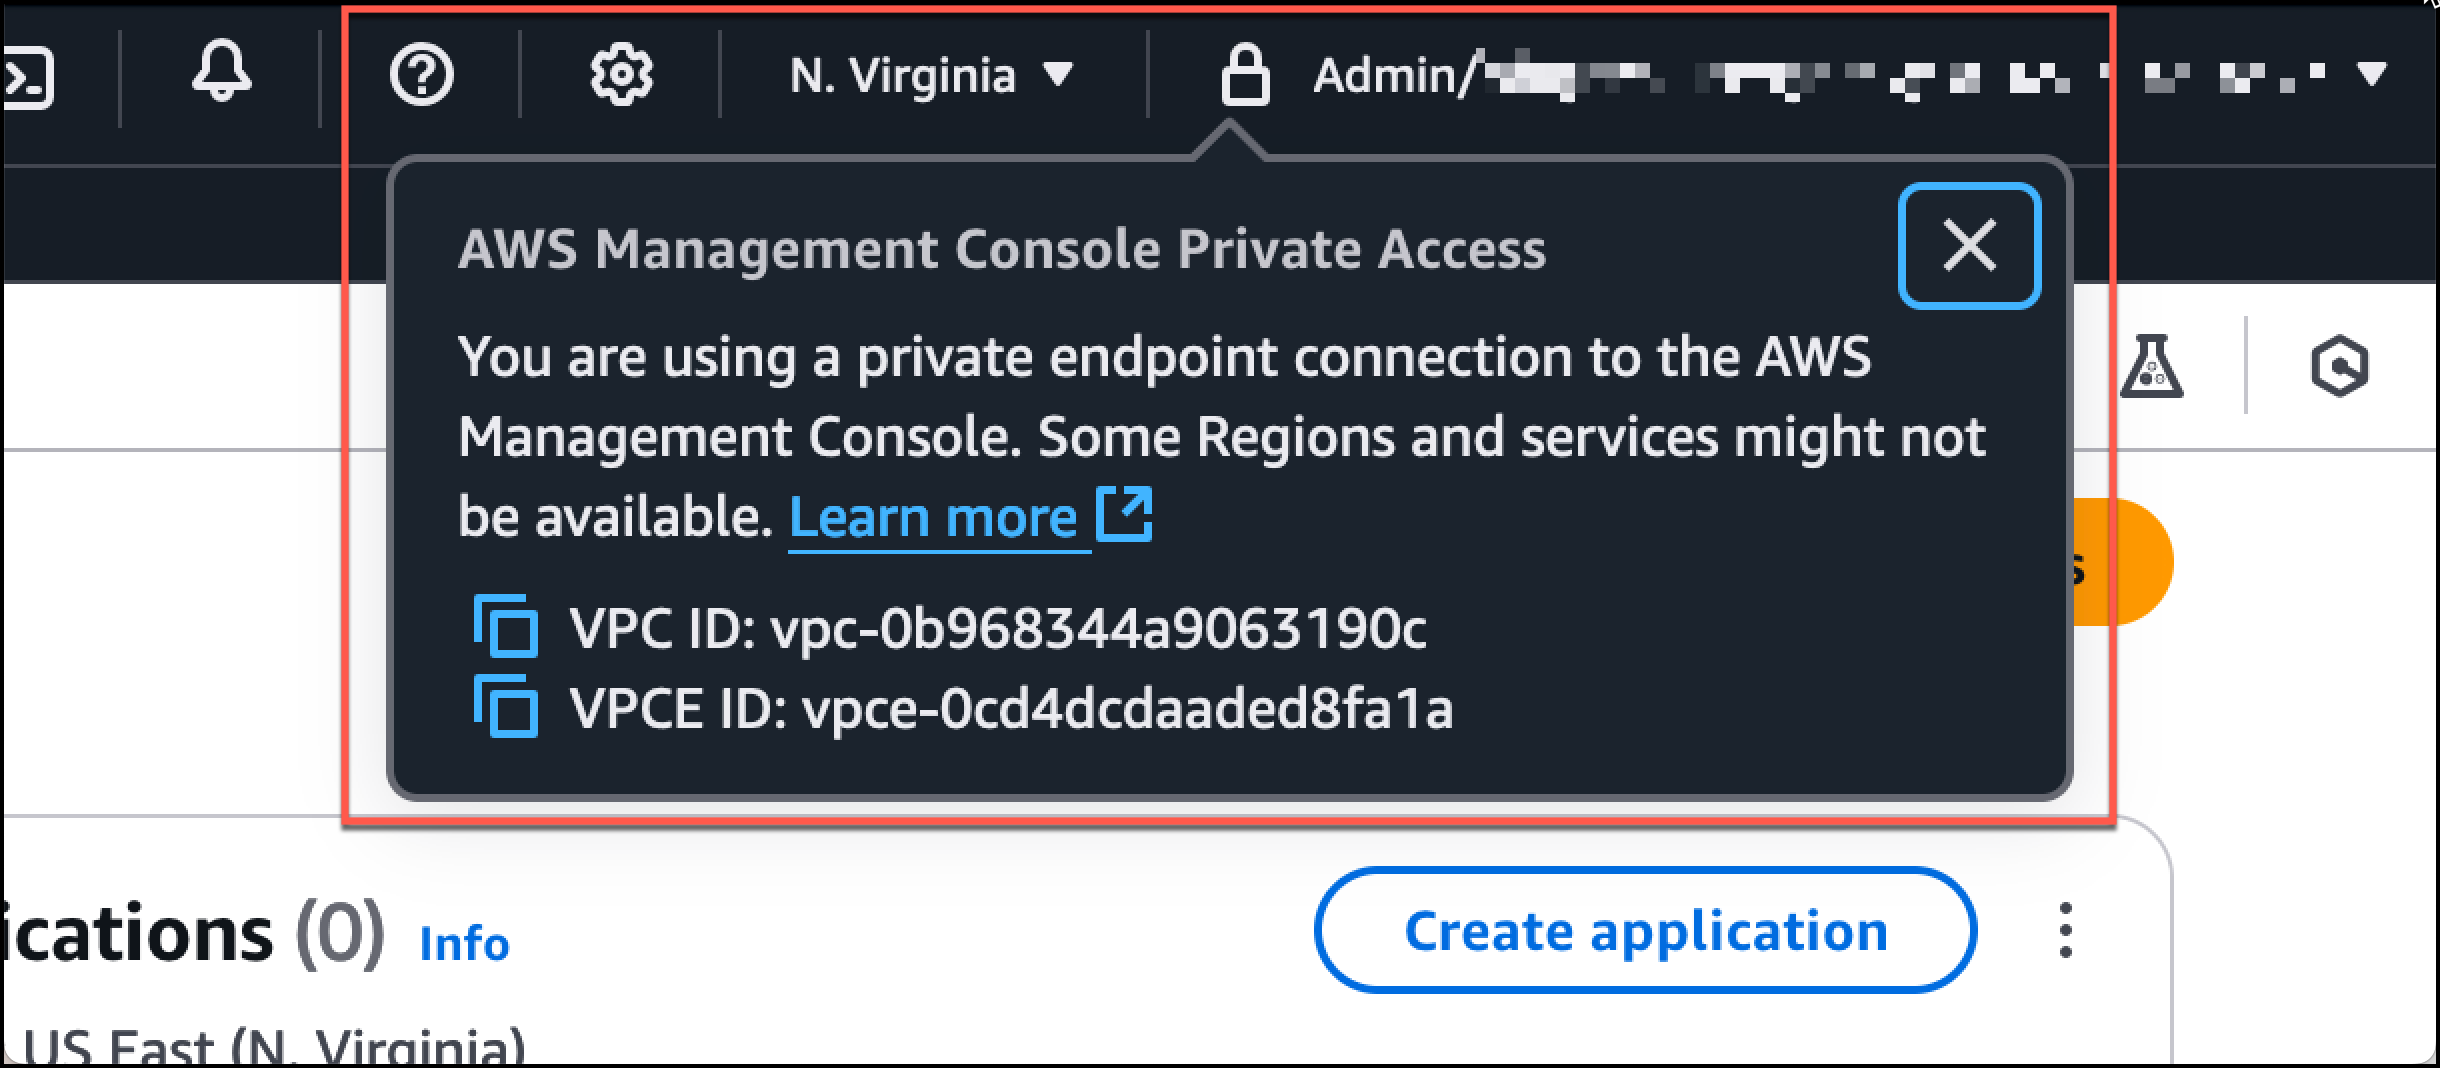
Figure 2: Console Private Access

Figure 2: Console Private Access

You can also verify in CloudTrail that recent ConsoleLogin events show the vpcEndpointId field populated with one of your endpoint IDs. Here’s an example CloudTrail ConsoleLogin event snippet showing the vpcEndpointId field:

{
  "eventVersion": "1.08",
  "userIdentity": {
    "type": "AssumedRole",
    "principalId": "AROA3XFRBF23EXAMPLE:john.doe",
    "arn": "arn:aws:sts::123456789012:assumed-role/Admin/john.doe",
    "accountId": "123456789012"
  },
  "eventTime": "2026-07-08T19:15:32Z",
  "eventSource": "signin.amazonaws.com",
  "eventName": "ConsoleLogin",
  "awsRegion": "us-east-1",
  "sourceIPAddress": "10.0.1.47",
  "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7)...",
  "requestParameters": null,
  "responseElements": {
    "ConsoleLogin": "Success"
  },
  "additionalEventData": {
    "LoginTo": "https://console.aws.amazon.com/console/home",
    "MobileVersion": "No",
    "MFAUsed": "Yes",
    "vpcEndpointId": "vpce-0abc123def456789a"
  },
  "eventID": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111",
  "eventType": "AwsConsoleSignIn",
  "recipientAccountId": "123456789012"
}

If the AWS Management Console doesn’t load, work through the following checks.

Private DNS is enabled on each interface endpoint (or your custom resolver returns the endpoint addresses)

When Private DNS is enabled, AWS automatically creates the DNS entries that resolve the service domains (such as console.aws.amazon.com) to the private IP addresses of your VPC endpoints. Without it, your browser still routes to the public AWS endpoints, bypassing your private access setup entirely.

  1. Confirm that each endpoint shows PrivateDnsEnabled:
    aws ec2 describe-vpc-endpoints \
    --filters "Name=vpc-endpoint-type,Values=Interface" \
    --query "VpcEndpoints[].{Id:VpcEndpointId,Service:ServiceName,PrivateDns:PrivateDnsEnabled}" \
    --output table
    

  2. Then, from within your VPC, verify that the domains resolve to private addresses:
    nslookup console.aws.amazon.com
    nslookup signin.aws.amazon.com
    
    # Should return a private IP (e.g., 10.x.x.x), not a public one
    

Each query should return a private IP address from your VPC CIDR range. If you use a custom DNS resolver instead of the Amazon-provided DNS, ensure your forwarding rules direct the AWS domain queries to the Route 53 Resolver inbound endpoints in your VPC.

The endpoint security groups allow HTTPS (TCP 443) from your workload subnets

Each VPC endpoint creates elastic network interfaces (ENIs) in your subnets, and these ENIs are governed by security groups. If those security groups don’t permit inbound HTTPS traffic from your workloads, the connection fails silently.

  1. Identify the security groups attached to your endpoints:
    aws ec2 describe-vpc-endpoints --vpc-endpoint-ids vpce-0abc123def456789a \
      --query "VpcEndpoints[].Groups[].GroupId" --output text
    

  2. Then verify that each security group allows inbound TCP 443 from your workload subnets:
    aws ec2 describe-security-groups --group-ids sg-xxxxxxxx \
      --query "SecurityGroups[].IpPermissions[?ToPort==\`443\`]" \
      --output json
    

For traffic from outside the VPC (Direct Connect or Site-to-Site VPN), corporate DNS returns the endpoint IPs and the route propagates correctly

If you access the console from an on-premises workstation connected over AWS Direct Connect or AWS Site-to-Site VPN, two additional conditions must be met.

  1. Your corporate DNS must resolve the AWS domains to the VPC endpoint private IPs. From your on-premises machine, run:

    nslookup console.aws.amazon.com

    If this returns public AWS IPs, your corporate DNS isn’t forwarding queries through Route 53 Resolver. Configure conditional forwarding for the aws.amazon.com and amazonaws.com domains to your Resolver inbound endpoint IPs.

  2. Second, network routes must propagate correctly. Ensure the route table associated with your endpoint subnets has propagated routes from your virtual private gateway (VGW) or transit gateway, so return traffic can reach your on-premises network. Verify this with:
    aws ec2 describe-route-tables \
      --filters "Name=association.subnet-id,Values=subnet-xxxxx" \
      --query "RouteTables[].PropagatingVgws"
    

A quick end-to-end validation: Run traceroute console.aws.amazon.com from your workstation and confirm the path uses private hops only—no traffic should traverse the public internet.

If the console loads but the lock icon is missing

If the console loads but the connection isn’t private (for example, the lock icon is missing), the browser is reaching the console over the public internet instead of through your VPC endpoints.

  • Run nslookup console.aws.amazon.com from a workload inside the VPC. The result should be a private IP from your VPC CIDR range. A public IP means DNS is bypassing the endpoint, which usually happens because Private DNS has not been enabled on the interface endpoint (set PrivateDnsEnabled = true).
  • For workloads outside the VPC, make sure your corporate DNS forwards the console domains into the VPC, for example, through an Amazon Route 53 Resolver inbound endpoint.

Step 5: Apply VPC endpoint policies

Attach an endpoint policy to the console and AWS Sign-In endpoints that limits access to identities in your organization. The static-content endpoint doesn’t support endpoint policies.

Begin with a permissive Allow * policy and confirm that traffic routes through the endpoints (you should see the vpcEndpointId field populated in CloudTrail console events). After confirming the routing, add restrictions to your VPC endpoint policy and observe the traffic.

A starter policy uses two condition keys: aws:PrincipalOrgID to restrict identities to your organization and aws:ResourceOrgID to restrict the resources the console can reach to your organization’s resources. The full reference, including additional condition keys and resource-restriction patterns, is in the AWS Management Console Private Access user guide.

For policies beyond the pilot, see Data perimeters on AWS. The data perimeter policy examples GitHub repository covers service-specific considerations for implementing data perimeters in your environment.

Step 6: Apply a Sign-In policy

Sign-In policies deny console authentication requests that don’t match your network or principal conditions. The policy is composed of a pre-authentication statement covering signin:Authenticate and a post-authentication statement covering signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token. Include both statements.

For your pilot, deploy the policy as an RCP from your AWS Organizations management account. When enabled, the RCP applies to all accounts in your organization, so we recommend piloting in a dedicated test organization before rolling it out broadly. Activate enforcement by calling the signin:PutConsoleAuthorizationConfiguration API for the organization in the us-east-1 Region (AWS Sign-In replicates policies globally from there). Resource permission statements have no effect until console authorization is enabled.

Important: Configure at least one excluded principal as a break-glass path before you enable the RCP. The recommended principal is a dedicated IAM role.

  1. Write the permission statements that define the network conditions:
    Example – Restrict access to corporate VPC:

    aws signin put-resource-permission-statement \
      --source-vpc vpc-0abc123def456789 \
      --requested-region us-west-2 \
      --excluded-principal "arn:aws:iam::123456789012:user/EmergencyAdmin" \
      --region us-east-1
    

    Example – Restrict access to specific IP range:

    aws signin put-resource-permission-statement \
      --source-ip "IP_ADDRESS" \
      --excluded-principal "arn:aws:iam::123456789012:role/BreakGlassRole" \
      --region us-east-1
    

  2. Enable console authorization for the organization to start enforcing the policy.
    aws signin put-console-authorization-configuration \
      --target-id <your-target-id> \
      --region us-east-1
    

  3. Review the consolidated policy that’s now in effect: 
    aws signin get-resource-policy --region us-east-1
    

For policy examples, the AWS Command Line Interface (AWS CLI) reference, and the lockout-recovery procedure, see the sign-in RBP blog post and the Controlling console access with resource-based policies documentation. The same documentation also covers the per-account alternative, which uses an RBP attached to a single account instead of an organization-wide RCP.

Step 7: Add a service VPC endpoint

So far, the console shell loads, the lock icon appears, and your Sign-In policy lets approved identities through. If you sign in to a service console such as the AWS Key Management Service (AWS KMS) console, the page might fail to load resources or hang. The Private Access endpoints carry the console shell, not the service API calls that the console makes on your behalf. In a VPC without an internet gateway, those calls have nowhere to go.

Add a VPC endpoint for the service itself. For the pilot, create an AWS KMS interface endpoint (com.amazonaws.<region>.kms) in the same VPC, with Private DNS enabled. Open the AWS KMS console from inside the VPC and confirm the list of keys loads. Repeat for each service your users need on day one. Please note that a single service console often calls more than one AWS service API. If a console loads but parts of the page show errors or stay empty, the most common cause is a missing endpoint for one of the services it depends on.

The current list of services that support PrivateLink is in the AWS PrivateLink documentation. Service consoles whose services don’t support PrivateLink will not work in a no-internet VPC and need to be handled separately.

Step 8: Hide Regions and services you haven’t configured (optional)

Console links to a service or Region that you don’t have endpoints for will fail inside your VPC. To prevent users from navigating to broken pages, use User Experience Customization (UXC) to hide Regions and services that aren’t part of your Private Access deployment. UXC is configured at the account level and applies to navigation, search results, and service-selection drop-downs.

Step 9: Validate, then expand

After applying the endpoint policies and the Sign-In RCP to one pilot account:

  1. Sign in from inside the corporate network. The session should succeed.
  2. Sign in from outside the corporate network. The session should be denied at the Sign-In step, before reaching the console.
  3. In CloudTrail, confirm ConsoleLogin events show vpcEndpointId populated for traffic from inside the network.
  4. For unexpected denials, look in CloudTrail for ConsoleLogin events with the error message Authorization denied because of a resource-based policy or Authorization denied because of a resource control policy to identify which statement was responsible.

Considerations

A few items worth mentioning before you commit to this design:

  • AWS IAM Identity Center: IAM Identity Center sign-in support isn’t yet available through a VPC endpoint. Initial single sign-on (SSO) authentication must still transit over the internet.
  • Programmatic access: Sign-In RBPs and RCPs gate interactive console sign-in. AWS SDK and AWS CLI requests signed with SigV4 aren’t affected. This is also your recovery path: a principal with signin:DeleteConsoleAuthorizationConfiguration permission can disable enforcement programmatically if console authorization is misconfigured.
  • Apps integrated with AWS Sign-In: Sign-In policies also apply to Amazon ConnectAmazon WorkSpacesAmazon QuickSightAWS Health DashboardAmazon AppStream 2.0, and Amazon Lightsail when those applications use AWS Sign-In to authenticate.
  • AWS Management Console Private Access is available in all commercial AWS Regions but supports only a subset of AWS service consoles. See Supported AWS Regions, service consoles, and features in Private Access documentation for more information.
  • For services that aren’t supported, you can still navigate to other consoles, but will require internet connectivity for the unsupported service consoles and console-only APIs.
  • Costs: You pay regular AWS PrivateLink endpoint pricing and data processing for each endpoint and each Region you deploy in. The three Private Access endpoints (consolesignin, and console-static) plus the service endpoints you already use are the relevant line items.

Conclusion

In this post, we showed you how to extend the AWS data perimeter framework to the AWS Management Console. You routed console traffic through VPC endpoints with AWS Management Console Private Access, restricted console sign-in by network and organization with Sign-In RBPs and RCPs, and configured the console to operate in a VPC without an internet gateway. The four control objectives that you already enforce for API traffic now also apply to the console.

To get started, see the AWS Management Console Private Access documentation. For deployment patterns and Region-by-Region considerations, see the AWS Management Console Private Access reference architectures. For background on the broader pattern, see Establishing a data perimeter on AWS.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the IAM forum on AWS re:Post or contact AWS Support.

Madhur Kulkarni

Madhur Kulkarni

Madhur is a Sr. Customer Solutions Manager at AWS, working with Strategic Accounts customers to accelerate cloud adoption and drive business outcomes. He partners with cross-functional teams across customer engineering, AWS service teams, and specialists organizations to deliver enterprise-scale cloud solutions.

Mateusz Jaworski

Mateusz Jaworski

Mateusz is a Principal Engineer at AWS, where he works on AWS Management Console.

Sujay Ghosh

Sujay Ghosh

Sujay is a Software Development Manager at AWS, where he leads a team responsible for enabling secure, reliable access to the AWS Management Console. He is passionate about building scalable infrastructure that helps millions of customers manage their cloud resources safely and efficiently.

Abhijit Barde

Abhijit Barde

Abhijit is a Principal Product Manager at AWS, where he focuses on making it straightforward for all AWS users to discover, monitor, and operate their AWS infrastructure using conversational assistants and generative AI.

[$] The “rnull” Rust block driver

Post Syndicated from daroc original https://lwn.net/Articles/1090378/

The
null block
driver
(null_blk)
is a small driver that is mostly useful for benchmarking block-layer
implementations. It accepts all requests and marks them complete as quickly as
possible, doing as little work as possible. In June 2026, Andreas Hindborg shared

a patch set
implementing the same functionality in Rust, in order to show
that a simple block driver is now possible to write using the kernel’s
Rust APIs and to enable comparisons between the C and Rust
implementations.
A minimal version of the “rnull” driver is already present in the mainline
kernel, but Hindborg’s patch set brings it up to feature parity with the C
version.

Razor Group’s journey to a modern data lakehouse on AWS

Post Syndicated from Yaswanth Kothainti original https://aws.amazon.com/blogs/big-data/razor-groups-journey-to-a-modern-data-lakehouse-on-aws/

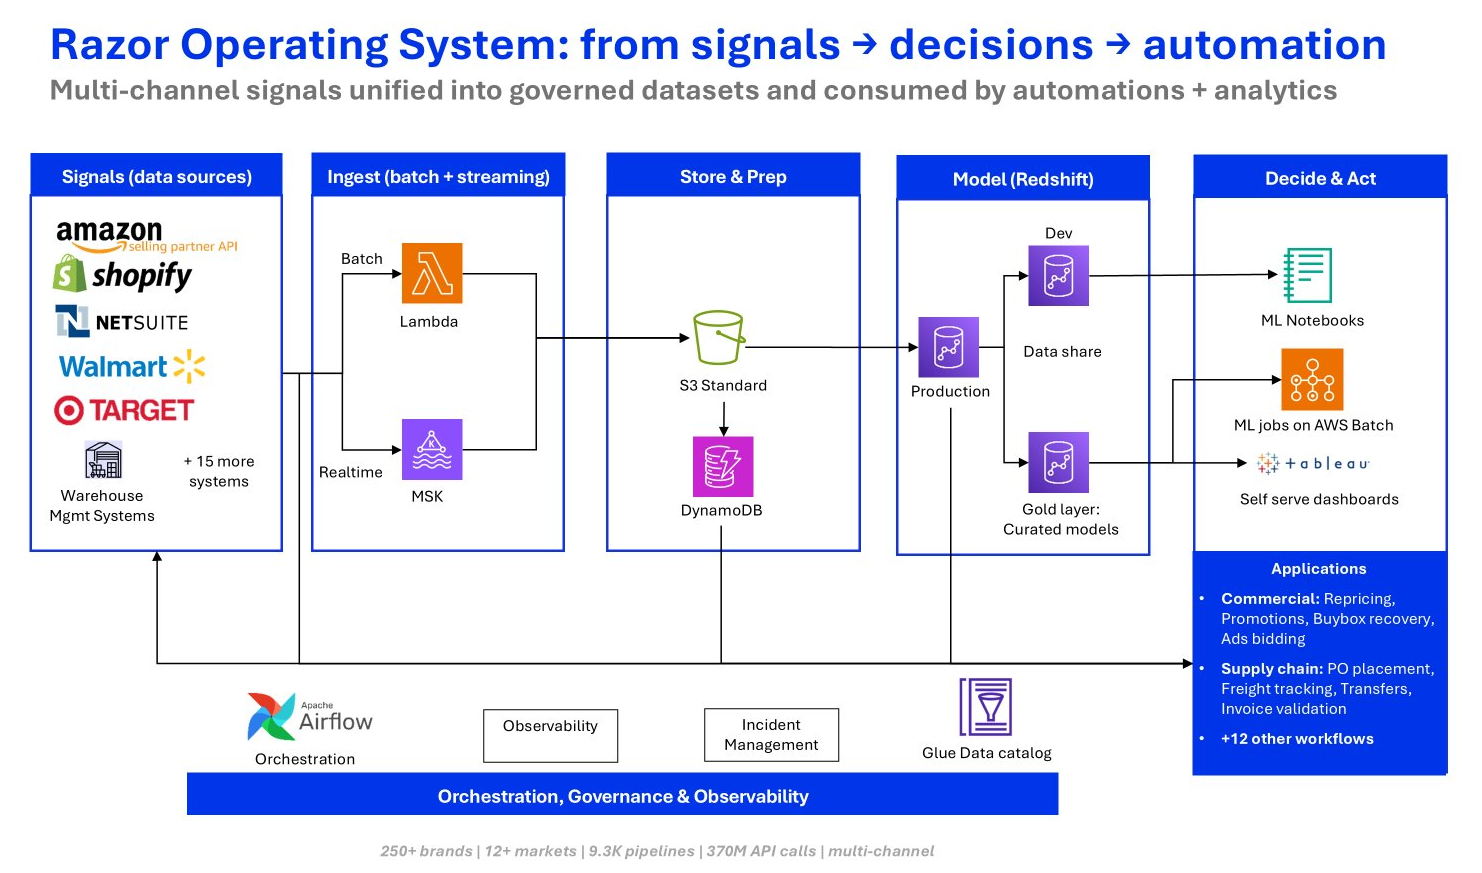
Razor Group is one of Europe’s leading ecommerce aggregators, operating 250+ brands across multiple global marketplaces. With a portfolio exceeding $400M in revenue, the company relies on data to power every critical business decision, from dynamic pricing and inventory optimization to advertising spend and supply chain orchestration.

At the heart of this operation sits the Razor Operating System (ROS), a proprietary platform that processes 370M+ API calls monthly through 9,300+ data pipelines, transforming marketplace signals into automated actions at scale.

In this post, we share how Razor Group optimized their data platform by implementing a lakehouse architecture on AWS. We cover the architectural decisions, the phased migration approach, and the measurable business outcomes. Whether you’re looking to optimize workload performance, reduce infrastructure costs, or unlock multi-engine flexibility for your analytics, this blueprint provides actionable insights you can adapt for your organization.

The business challenge: Scaling data infrastructure for hypergrowth

As Razor Group’s brand portfolio expanded rapidly, the demands on their data platform grew significantly. The company needed their analytics infrastructure to keep pace with the speed of ecommerce, where pricing decisions, stock replenishment, and advertising bids happen in near real time.

Their existing architecture, built on Amazon Redshift provisioned clusters, had served them well during earlier growth stages. As workloads diversified and data volumes surged, several optimization opportunities emerged:

Razor Operating System data architecture before the migration: signal sources such as Amazon Selling Partner API, Shopify, NetSuite, Walmart, and Target ingested through AWS Lambda and Amazon MSK, stored in Amazon S3 and Amazon DynamoDB, modeled in Amazon Redshift, and consumed by ML notebooks, ML jobs on AWS Batch, and Tableau dashboards, orchestrated by Apache Airflow

Figure 1: The Razor Operating System data architecture before the migration

  • Workload contention: Over 1,000 SQL models for ETL, transformation, and analytics competed for the same compute resources, creating resource contention during peak processing windows.
  • Cost-to-utilization mismatch: Always-on clusters ran 24/7, but workload analysis revealed that 98% of compute demand came from batch ETL rather than interactive analytics, which resulted in significant idle capacity during off-peak hours.
  • Data freshness gaps: Batch-oriented pipelines delivered data with 4–6 hour latency, limiting the team’s ability to react to fast-moving marketplace dynamics.
  • Scaling constraints: As concurrent users and pipeline complexity grew, vertical scaling alone couldn’t address the need for workload isolation and elastic capacity.

These weren’t failures of any single service. They were signals that the architecture needed to evolve to match the scale and diversity of Razor Group’s workloads.

Why a lakehouse architecture?

Rather than replacing their existing investments, Razor Group recognized the opportunity to optimize workload placement by adopting a modern lakehouse architecture. The core principles driving this decision:

  • Open table formats: Apache Iceberg provides ACID transactions, time travel, and schema evolution. Data is stored once and accessed by any compatible engine without duplication.
  • Elastic, per-workload scaling: With data persisted on Amazon Simple Storage Service (Amazon S3), each engine independently scales compute to match its workload. Each engine spins up for peak processing and scales to zero when idle, without over-provisioning shared infrastructure.
  • Multi-engine flexibility: Different workloads have different requirements. Heavy ETL benefits from distributed Spark processing, ad hoc exploration from serverless queries, and business intelligence (BI) dashboards from high-performance warehouse engines, each optimized for its purpose.

This approach allowed Razor Group to right-size each workload to the best-fit engine while maintaining a single, governed copy of data accessible across the entire platform.

Solution overview

Razor Group partnered with AWS to implement a comprehensive lakehouse architecture that brings together multiple AWS services, each playing a complementary role:

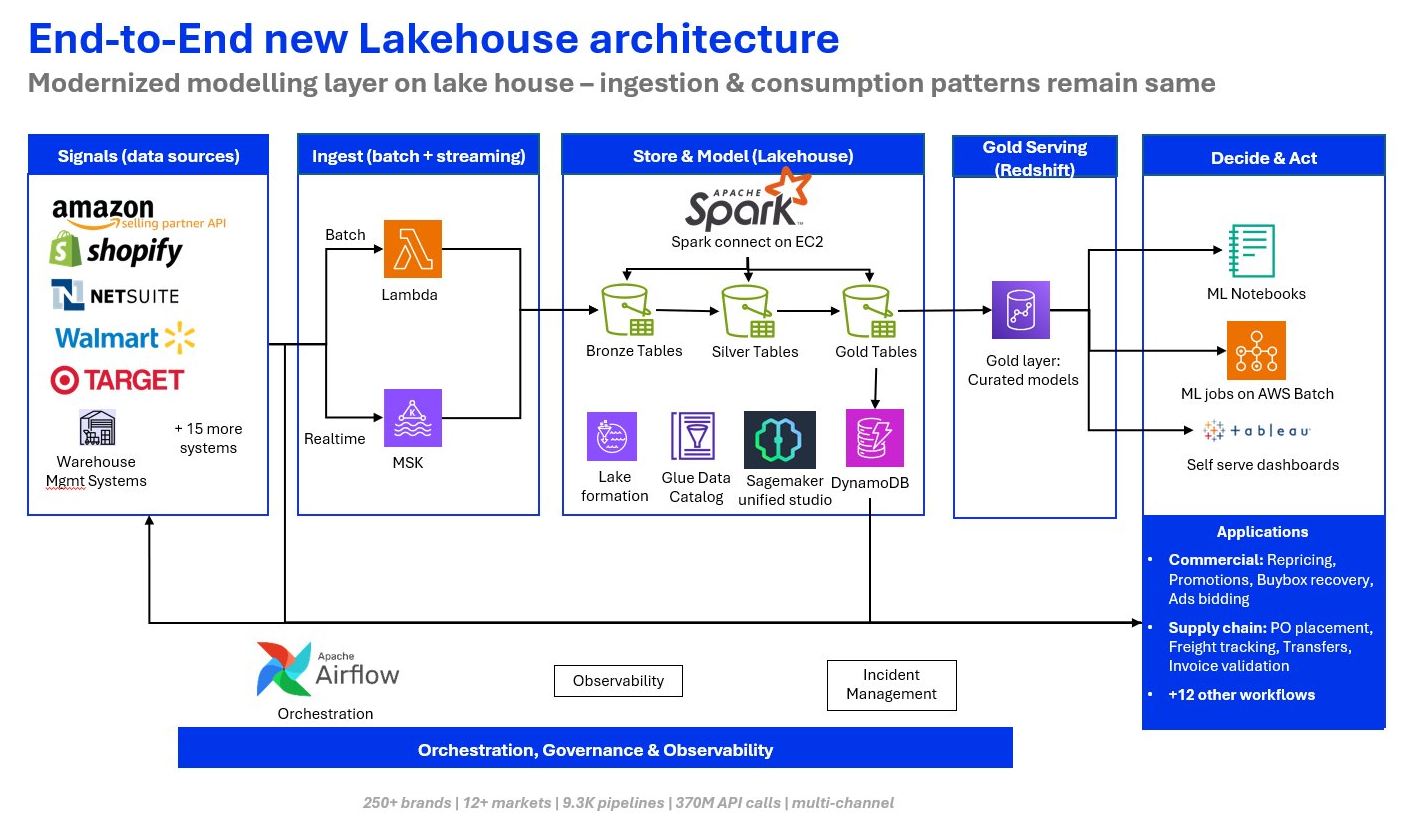
New lakehouse architecture on AWS: the same signal sources ingested through AWS Lambda and Amazon MSK, stored and modeled as Bronze, Silver, and Gold Apache Iceberg tables using Apache Spark Connect on Amazon EC2 with AWS Lake Formation and AWS Glue Data Catalog, served through Amazon Redshift, and consumed by ML notebooks, ML jobs on AWS Batch, and Tableau dashboards

Figure 2: End-to-end lakehouse architecture on AWS

Designing for scale: The lakehouse vision

The core insight driving Razor Group’s new architecture was simple: build a single, open format data lake that any engine can query. In the old model, each tool maintained its own copy of the data. In the new model, a single open-format data lake on Amazon S3 serves as the source of truth, and multiple purpose-built compute engines read from it based on the workload at hand.

This shift, commonly called a lakehouse architecture, combines the cost economics and scalability of a data lake with the query performance and governance of a data warehouse. Its open table format, Apache Iceberg, provides ACID transactions, schema evolution, time travel, and no vendor lock-in.

Storage and governance: The open data foundation

  • Amazon S3 Tables (a capability of Amazon S3) with Apache Iceberg — The primary storage layer, providing open-format tables with ACID transactions, partition evolution, and time travel. Data is stored once and accessible by any Iceberg-compatible engine.
  • AWS Glue Data Catalog — A unified metadata repository for consistent data discovery across all compute engines.
  • AWS Lake Formation — Fine-grained access control with column-level and row-level security so that governance scales with the platform.

Compute: Right engine for the right workload

  • Apache Spark on Amazon Elastic Compute Cloud (Amazon EC2) — Elastic, distributed compute for heavy ETL and transformation workloads. It uses AWS Graviton instances and Amazon EC2 Spot Instances for cost optimization.
  • Amazon Athena — Serverless SQL for ad hoc exploration and lightweight queries directly on Iceberg tables, with no infrastructure to manage.
  • Amazon Redshift Serverless — High-performance serving layer for BI dashboards, Tableau workloads, and interactive analytics. Amazon Redshift Serverless automatically scales to meet demand and pauses when idle, so it stays cost-efficient for the analytics workloads it serves best.

Orchestration and observability

  • Apache Airflow — Pipeline orchestration that manages 9,300+ data pipelines with dependency tracking and service level agreement (SLA) monitoring.
  • Comprehensive observability stack — Cost attribution, pipeline health monitoring, and data quality checks across all layers.

Note: When the architecture was originally designed, Amazon Redshift lacked Iceberg write support, making self-managed Spark the only viable ingestion path. This constraint has since been removed. Amazon Redshift now supports full Apache Iceberg DML (UPDATE, DELETE, MERGE), complementing its earlier CREATE/INSERT capabilities and AWS Glue Iceberg materialized views. This makes it a complete read/write Iceberg engine.

Migration approach

Rather than a risky big-bang cutover, Razor Group adopted a phased migration of five stages, each delivering standalone value while building the foundation for the next. Both Amazon Redshift and Spark pipelines ran in parallel during the transition, which maintained business continuity and let the team compare outputs with confidence. At no point was a production pipeline paused or a dashboard unavailable.

The migration journey: Five phases

The migration unfolded across five structured phases, each building on the previous one and delivering incremental value before the next began.

Phase 1: Establish the lakehouse foundation

Before migrating a single query, Razor Group needed to answer three questions: where does the data live, how is it managed, and how do we query it?

Why S3 Tables over self-managed Iceberg

Razor Group had already committed to Apache Iceberg as the table format: open, engine-agnostic, and equipped with ACID transactions and time travel. The question was whether to self-manage Iceberg on standard S3 buckets or use Amazon S3 Tables.

Self-managed Iceberg is powerful but operationally expensive. Someone has to run compaction jobs to prevent small-file proliferation. Someone has to expire old snapshots before metadata bloat degrades query planning. Someone has to clean up orphaned data files after interrupted writes. With 700+ models running across 40+ schemas, many of them materializing multiple times per day, that maintenance burden would scale with the platform rather than shrink.

S3 Tables eliminated this entire category of work. Compaction, snapshot management, and unreferenced file removal run continuously and automatically. The integrated Iceberg REST Catalog API means any compatible engine, such as Spark, Trino, Athena, Amazon Redshift, and Flink, can discover and query tables without maintaining a separate metastore. Discovery is unified through AWS Glue Data Catalog, which now exposes the Iceberg REST Catalog protocol as its access interface. Because tables are first-class AWS resources, access control, encryption, and lifecycle policies operate at the table level rather than through complex S3 bucket policies layered on top of file-path conventions.

For a company that didn’t want the operational burden of self-managing open table format maintenance, this was the deciding factor.

AWS Glue Data Catalog provides unified metadata discovery across all tiers. Lake Formation handles column- and table-level access control, with AWS Identity and Access Management (IAM) roles that follow least-privilege principles and AWS CloudTrail turned on for a full audit trail.

Choosing the query protocol

Prior to the rearchitecture, the Amazon Redshift cluster was 98% ETL, and only a fraction of compute hours were analyst SELECT queries. The replacement engine needed to handle both heavy batch transformations and interactive ad hoc queries.

Traditional Spark (spark-submit) handles batch ETL well, but couples clients to the cluster. Every job requires packaging driver JARs, managing classpaths, and submitting from within the cluster. For a platform running 200+ production directed acyclic graphs (DAGs) that process massive data volumes daily, this operational friction was a non-starter.

Spark Connect is the gRPC-based client-server protocol introduced in Spark 3.4, and it solved the coupling problem entirely. The cluster runs a persistent gRPC endpoint. Clients connect remotely and submit queries over the wire. Airflow operators become thin clients: they open a session, submit SQL, and get results, with success and failure mapping directly to task states. There are no driver JARs and no polling. Multiple consumers, including pipeline orchestrators, the web application, and developer notebooks, share one cluster without any of them needing Spark installed locally.

Deploying Spark Connect

Razor Group deployed a self-hosted Spark cluster on Amazon EC2: an on-demand AWS Graviton leader node, Spot workers at about 70% cost savings, and the Spark Connect endpoint exposed through an internal Network Load Balancer. Custom Amazon Machine Images (AMIs) bake in the full Spark, Iceberg, and S3 Tables stack, so private-subnet nodes have everything they need without internet access at runtime.

This phase produced no immediate business value, but it made everything that followed possible.

Phase 2: Migrate data ingestion

Razor Group’s ingestion layer pulls data from Amazon Selling Partner API, Seller Central portals, NetSuite ERP, and custom web scrapers. In the previous architecture, all of this landed in Amazon Redshift through COPY commands, which meant data freshness was dictated by batch job schedules and competed for resources on the same cluster that served analytical queries.

Razor Group migrated these pipelines to AWS Lambda functions orchestrated by Apache Airflow, writing data directly to S3 Tables in Iceberg format. The shift from schedule-driven to event-driven significantly improved freshness. Lambda functions spin up only when there’s data to process, and Airflow sensors trigger downstream transformations the moment new data lands. This replaced rigid hourly batch windows with data freshness measured in minutes.

The orchestration layer manages 200+ DAGs across 90+ flows and processes data from dozens of sources at scale. The migration required rewiring destinations from Amazon Redshift COPY to Iceberg writes, but the orchestration logic itself carried over with minimal changes.

This phase alone eliminated roughly 40% of compute costs by severing the always-on cluster dependency for ingestion.

Phase 3: Transform processing pipelines

This was the most technically demanding phase, and where Razor Group learned the most. The team migrated 1,000+ SQL models from Amazon Redshift to Apache Spark, working incrementally up the dependency chain across 40+ schemas. The models moved through a medallion structure: Bronze for raw ingested data, Silver for cleaned and conformed data, and Gold for business-ready aggregates.

Razor Group built automated conversion tooling and a validation framework that ran both Amazon Redshift and Spark outputs in parallel, comparing results row-by-row before decommissioning anything. Several categories of transformation pushed the limits of what automation could handle:

  • Window functions: The QUALIFY clause in Amazon Redshift has no Spark equivalent. Each instance required wrapping in a subquery with explicit row numbering, which affected dozens of models in the inventory schema alone.
  • JSON serialization: The most time-consuming category. Complex columns stored as JSON STRING in Amazon Redshift needed from_json() with hand-written STRUCT definitions in Spark. Every nested payload column across ads, orders, and transaction pipelines required schema introspection, with no shortcuts.
  • Function dialect: More than 20 function-level conversions, including NVL to COALESCE, DATEADD to interval arithmetic, and LISTAGG to ARRAY_JOIN(COLLECT_LIST()).
  • Snapshot elimination: The single biggest hidden cost. Full table copies that ran multiple times daily only to preserve point-in-time state consumed more than 35 hours of weekly Amazon Redshift compute. With Iceberg’s native time travel, these became zero-cost operations overnight.

When migrating 1,000+ SQL models, automated tooling handles the mechanical syntax conversions well. But roughly 30% of the models required human judgment: those with complex JSON payloads, deeply nested window functions, or cross-schema snapshot dependencies. These models consumed 70% of the migration effort.
Razor Group built a structured migration workflow that used Claude to accelerate this work: read source SQL, identify dependencies, convert syntax, resolve missing base tables, add JSON parsing, validate outputs, and write to the lakehouse. The system did more than translate SQL. It applied schema context, traced cross-model dependencies, and flagged edge cases that would have taken engineers hours to find manually. What could have been a multi-year effort became a systematic, repeatable process measured in weeks. This approach fundamentally changed the speed of migration.

Phase 4: Unify the serving layer

With data flowing through Iceberg tables, Razor Group collapsed the serving layer. End users query Gold-layer Iceberg tables through Amazon Redshift Serverless, and internal exploration and machine learning (ML) workloads read the same tables through Spark Connect. This removed the need to maintain separate data copies, materialized views, or extract jobs for different consumers.

This is the strategic payoff of an open table format. Iceberg tables on S3 are engine-agnostic: Spark for batch transforms today, Trino for interactive queries tomorrow, Flink for streaming next quarter. Any engine that speaks Iceberg can read the data without conversion or migration. Razor Group went from being locked into a single vendor’s SQL dialect to having the freedom to adopt new engines without touching the storage layer.

Phase 5: Operationalize and observe

The final phase made the lakehouse production-grade. Razor Group built a comprehensive observability stack that aggregates metrics, traces, and logs from every pipeline component into a unified view. This view supports centralized log search, anomaly detection, and automated alerting that correlates failures across the entire data platform.

This observability layer did more than provide visibility. It gave the team confidence. When you’re running thousands of pipeline executions daily, you need to know within minutes when something breaks, what caused it, and which downstream consumers are affected. That’s the difference between reactive firefighting and proactive operations.

Pipeline orchestration consolidated around three patterns: a daily pipeline (ingestion to materialization to export to AI agent analysis), an operations worker polling every 15 minutes, and weekly scraper jobs.

The cutover was zero-downtime by design: both schedulers ran in parallel for two weeks. Automated comparison checks validated that every pipeline produced identical outputs before the prior architecture system was disabled.

Results and business impact

The lakehouse architecture delivered measurable improvements across every dimension:

Metric Before After Improvement
P95 query runtime 180 seconds 63 seconds 65% faster
Infrastructure cost Always-on provisioned clusters Elastic, workload-optimized 63% reduction
Data freshness 4–6 hour batch cycles Event-driven pipelines 15-minute freshness
Concurrent capacity Limited by cluster size Elastic, independent scaling Unlimited
Engine flexibility Single engine Multi-engine (Spark, Athena, Amazon Redshift) Open format portability

The 63% reduction compares the lakehouse run-rate (January–March 2026) with the pre-rearchitecture run-rate (October–December 2025), the trailing three months before the rearchitecture. The figure is an apples-to-apples blended infrastructure number that includes compute and storage across both architectures. The before column covers Amazon Redshift cluster compute and managed storage. The after column covers Amazon EC2 (Spark workers, both on-demand and Spot), AWS Lambda, AWS Glue, Amazon Athena, Amazon Redshift Serverless, and S3 Tables storage. Data-transfer and ancillary services are excluded because they were not materially different between the two periods. Workload mix (the number of pipelines, models, and end-user query volume) was held broadly comparable across the two windows.

Lessons learned

Start with the decision loops, not the tools, and know your workload before you replace your warehouse.

The most valuable activity of the entire migration wasn’t writing a line of code. It was the Amazon Redshift workload analysis we ran before making any architectural decisions. Discovering that 98% of compute was ETL, with only a sliver going to analyst queries, validated the move to on-demand Spark. It also prevented us from over-provisioning the replacement infrastructure for interactive workloads that barely existed. Architecture decisions should always trace back to core business requirements: pricing accuracy, promotional responsiveness, intraday P&L visibility. Start there, not with the technology.

Design for multiple compute engines, and choose the right engine per workload.

One of the clearest lessons from running a single-engine architecture is what you give up. Avoid locking yourself into one compute layer for BI, ingestion, backfills, and ML alike, because they have fundamentally different cost and performance profiles. Iceberg, Spark, and S3 Tables work well together out of the box once you make the shift. The technology isn’t the hard part. The hard part is mapping 1,000+ models across 40+ schemas, tracing dependencies through 200+ DAGs, and discovering that a column is actually a JSON string silently serialized differently between two engines. Migration is as much an excavation project as an engineering one.
Automate conversion, but budget for the 30%.

Automated tooling handles mechanical syntax conversions well, and it should be the first tool you reach for. But models with complex JSON payloads, deeply nested window functions, or cross-schema snapshot dependencies require human judgment, and that work doesn’t compress. Roughly 30% of our models needed significant manual intervention, and those models consumed 70% of the total migration effort. Plan for it honestly from the start.
Observability must include cost attribution, and watch out for hidden cost bombs.

Snapshot operations were our biggest surprise. Full table copies that ran multiple times daily to preserve point-in-time state were costing more than 35 hours of weekly compute, and nobody questioned it because “that’s how snapshots work.” Iceberg’s time-travel capability eliminated their cost, and that single feature justified a meaningful portion of the migration on its own. More broadly, you cannot optimize what you cannot see, so track query-level usage and attribute it to teams and functions. Cost observability is not a nice-to-have. It’s foundational.

Governance isn’t optional. Build it into the foundation, and align stakeholders from day one.

Catalog and access control need to come first, before you scale adoption, not after. The same principle applies to people: migration is a cross-functional program, not an infrastructure project. Our two-week parallel run caught edge cases that row-level validation missed entirely: time zone differences between Amazon Redshift and Spark, partition pruning behavior under concurrent writes, and subtle ordering differences in non-deterministic window functions. That parallel run wasn’t a safety net. It was where the migration actually proved itself. None of it works without the right stakeholders involved and aligned from the very beginning.

Conclusion

Razor Group’s journey offers valuable lessons for organizations looking to optimize their data architectures:

  1. Analyze your workload mix first. Understanding that 98% of compute was ETL rather than interactive queries guided the decision to offload heavy processing to elastic Spark, while preserving Amazon Redshift Serverless for the interactive analytics it handles best.
  2. Design for multi-engine flexibility. Open table formats like Apache Iceberg eliminate the need to choose a single engine. Each workload runs on the engine best suited to its access pattern, cost profile, and performance requirements.
  3. Automate migration, but budget for complexity. Automated transpilation handled 70% of SQL models, but the remaining 30% consumed 70% of engineering effort. Plan accordingly.
  4. Observability must include cost attribution. Without per-workload cost visibility, optimization is guesswork. Razor Group discovered that Iceberg snapshot maintenance alone consumed more than 35 hours of compute weekly, a hidden cost that observability surfaced and automation resolved.
  5. Build governance into the foundation. AWS Lake Formation and AWS Glue Data Catalog provided fine-grained access control from day one, not retrofitted after the migration.
  6. Validate with parallel systems. A two-week parallel run between old and new architectures caught edge cases that automated testing missed, which supported a confident production cutover.

The road ahead

With the lakehouse foundation in place, Razor Group is positioned to accelerate innovation, from real-time pricing models to AI-driven inventory optimization, all powered by a unified, open, and governed data platform on AWS.

The company’s transformation demonstrates that modern data architectures aren’t about choosing between services. They’re about placing each workload where it performs best, using open formats to eliminate silos, and scaling each layer independently as the business grows.

To learn how other organizations are implementing similar lakehouse architectures on AWS, see How BigBasket uses the Iceberg-based lakehouse architecture on AWS to power lightning-fast grocery delivery across India.


About the authors

Yaswanth Kothainti

Yaswanth is VP of Data Engineering & Platform at Razor Group, a $400M+ ecommerce enterprise, where he built the company’s data platform from the ground up and leads a 65-member global engineering organization. His core expertise spans enterprise data platforms, data governance, FinOps, and agentic AI systems, with a track record of translating complex platform investments into measurable business outcomes.

Shubham Purwar

Shubham Purwar

Shubham is an Analytics Specialist Solutions Architect at AWS. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on AWS. In his free time, Shubham loves to spend time with his family and travel around the world.

Ravi Kompella

Ravi Kompella

Ravi is Principal Analytics Specialist with experience in driving adoption of modern data architectures, enterprise data lakehouses, and real-time data systems across multiple industry verticals in India across all segments including startups and SaaS providers.

How to build a serverless mass email solution with Amazon SES

Post Syndicated from Brad Watson original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-build-a-serverless-mass-email-solution-with-amazon-ses/

Sending mass email campaigns presents significant challenges for many organizations. Enterprises often spend millions annually on proprietary email systems that are inflexible and expensive to maintain. These legacy platforms can restrict sending capacity, offer limited control, and require costly licensing agreements. The challenges intensify when handling large-scale communications like automated notifications, bulk marketing campaigns, and system-generated alerts. These scenarios create reliability issues, scaling limitations, and rising costs that impact teams’ ability to communicate effectively with customers.

Recently, a large federal organization faced similar challenges, spending over a million dollars annually on their email campaigns. By building a custom email solution on AWS, they sent a 2 million email campaign for approximately $300. This cost includes Amazon Simple Email Service (Amazon SES) and other AWS services. This transformation cut costs while providing the scalability and flexibility they needed for their growing campaign needs.

This transformation succeeded because building a cloud-native serverless mass email solution offers several advantages:

  • Cost optimization.
    • Pay only for email sent and actual compute resources used.
    • Remove costs associated with managing email servers.
    • Remove expensive licensing fees and maintenance overhead.
  • Scalability and reliability.
    • Automatically handle varying email volumes without infrastructure changes.
    • Support reliable delivery through built-in retry mechanisms and error handling.
    • Perform consistently during peak sending periods.
  • Security and compliance.
    • Secure access control through AWS Identity and Access Management (IAM) roles with least-privilege principles.
    • Comprehensive audit trails for all email campaigns with detailed logging to support your reporting requirements.
    • Detailed logging that customers can use for their compliance and reporting requirements.
    • Data encryption in transit and at rest that you can configure.

In this post, we explore the architecture of a cloud-native serverless mass email solution that integrates Amazon SES with AWS Step Functions, Amazon API Gateway, and Amazon DynamoDB. You will learn how these services work together to process email campaigns at scale while minimizing cost. Let’s get started!

Solution overview

The serverless mass email solution consists of two main components: a user-friendly frontend interface and a scalable serverless backend. The frontend operates completely independently from the backend processing system, communicating through RESTful APIs from Amazon API Gateway. With this architecture, you can use the provided frontend interface as-is. Alternatively, you can integrate your own custom UI or existing applications while using the same backend email processing infrastructure.

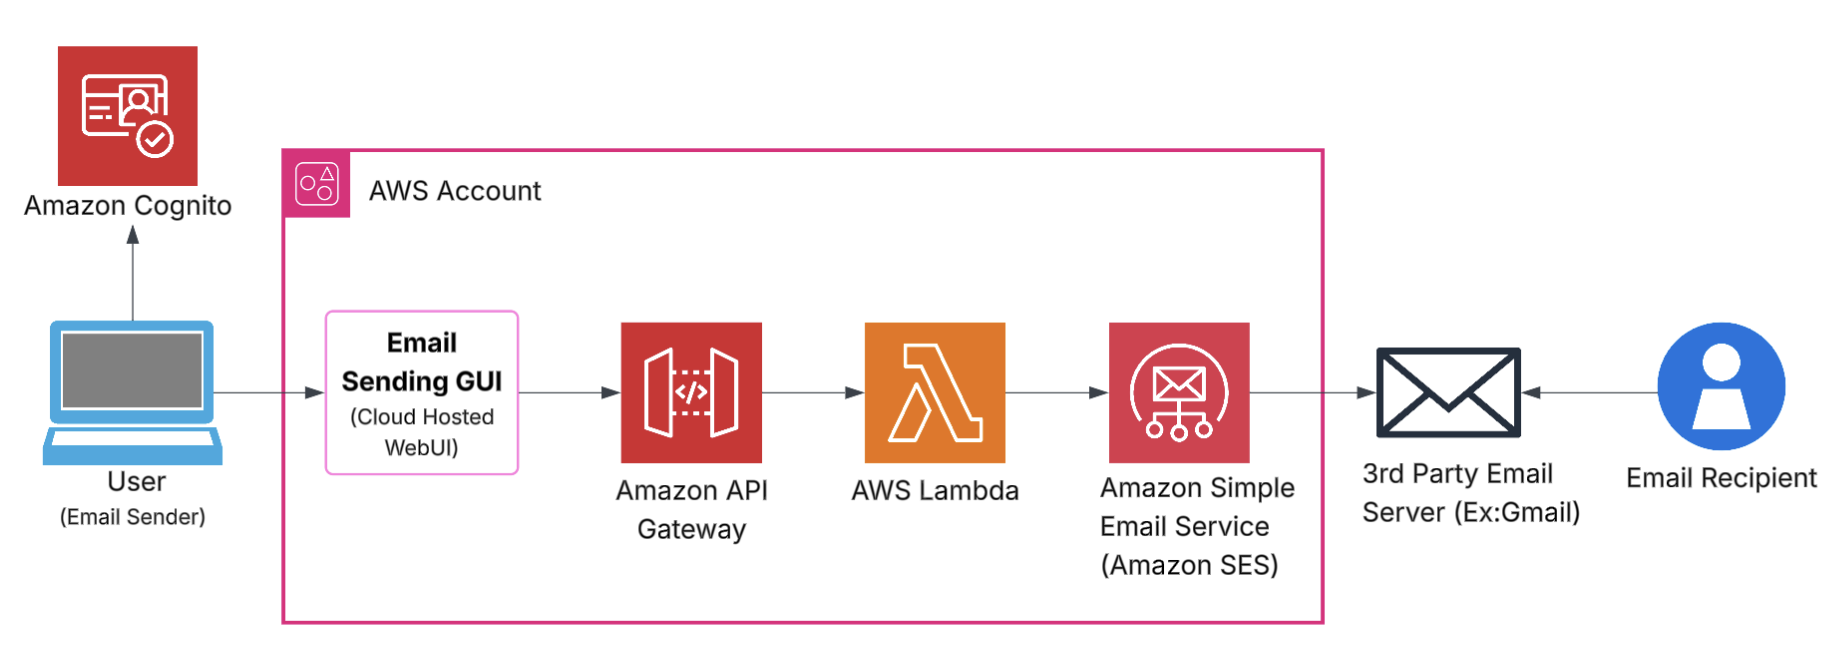
The following diagram shows the complete architecture of the serverless mass email solution, including how the frontend and backend components connect through API Gateway to process email campaigns.

Complete serverless mass email architecture, with the frontend and backend connected through Amazon API Gateway

Figure 1: Complete architecture

Frontend architecture and user flow

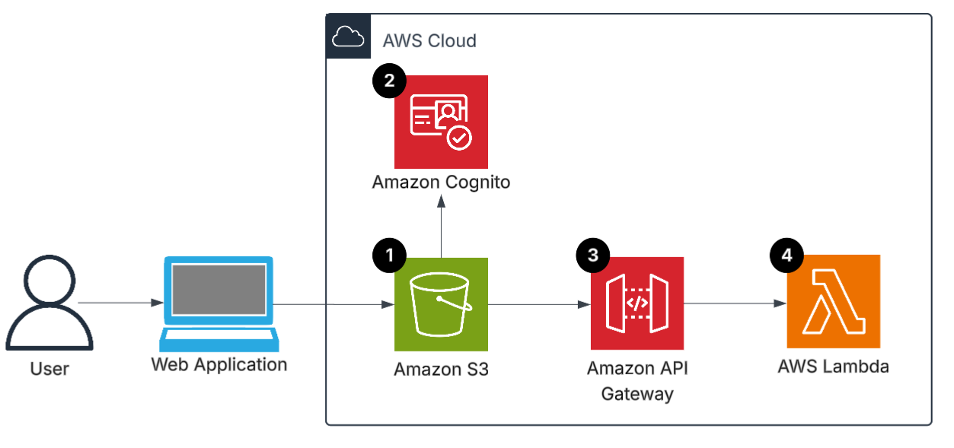
The frontend of the solution prioritizes usability while providing email campaign capabilities. Here’s how the components work together:

Frontend architecture: web interface, Amazon Cognito authentication, and requests through API Gateway to AWS Lambda

Figure 2: Frontend architecture of the SES email application

  1. Login – Users navigate to the web interface URL (hosted on Amazon Simple Storage Service (Amazon S3)) which prompts them to authenticate.
  2. User authenticationAmazon Cognito handles authentication, providing secure user management and restricting access to authorized users.
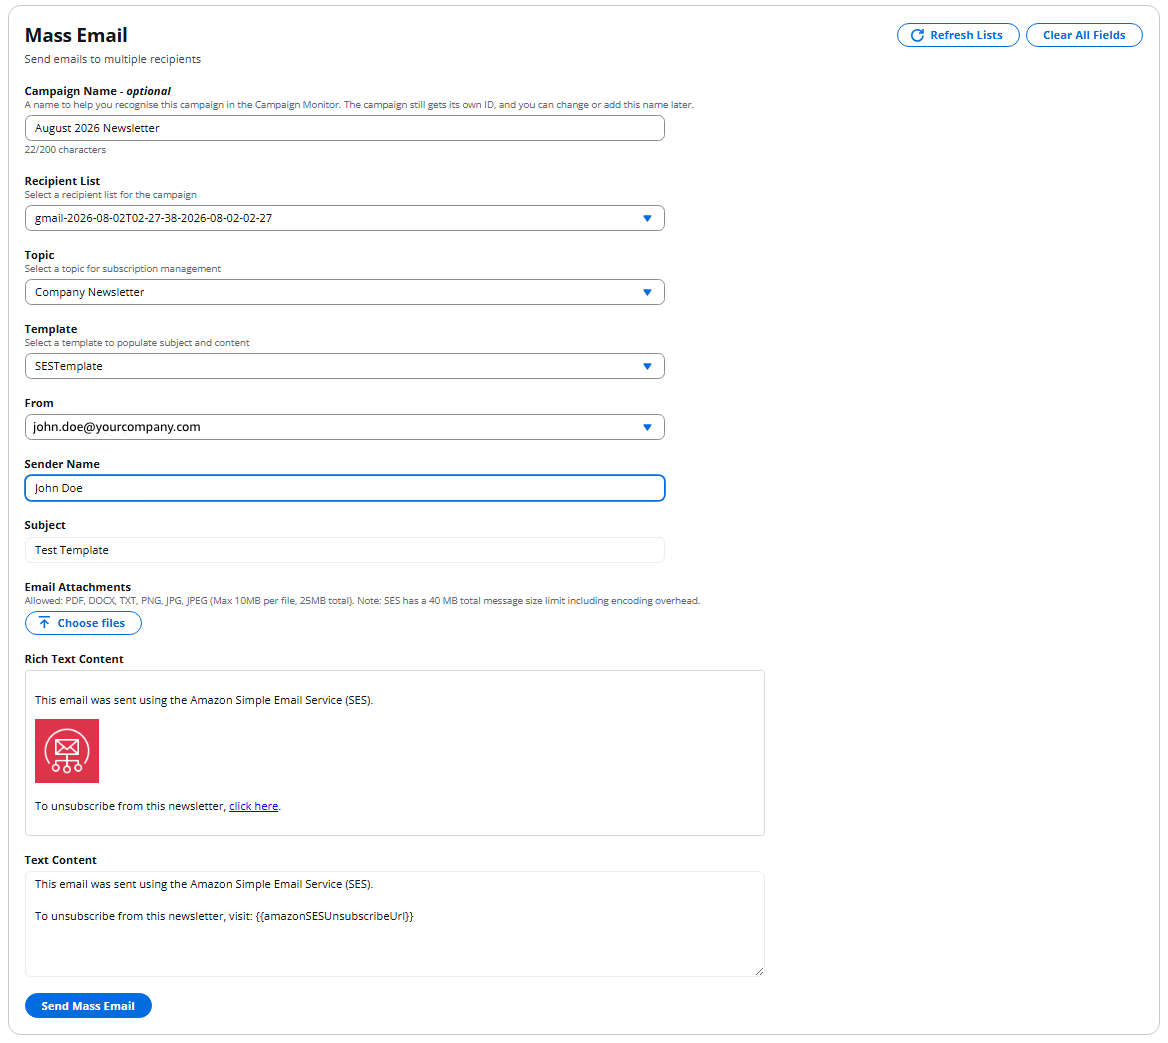
  3. User interface – After successful authentication, users are redirected to a graphical user interface (GUI) where they can design and save email templates and launch large-scale campaigns (refer to figures 3 and 4).
    1. Templates.
      1. Amazon SES supports two types of templates: stored and inline. Stored templates live in SES, and you can reuse them across campaigns. With inline templates, you define the content and variables directly in the email sending request. Both approaches support dynamic personalization by replacing variables with recipient-specific data when the email is sent. For example, you can create a template that personalizes each email with the recipient’s name, custom offers, or any other dynamic content. For detailed information about template capabilities and personalization options, refer to the Amazon SES template documentation.

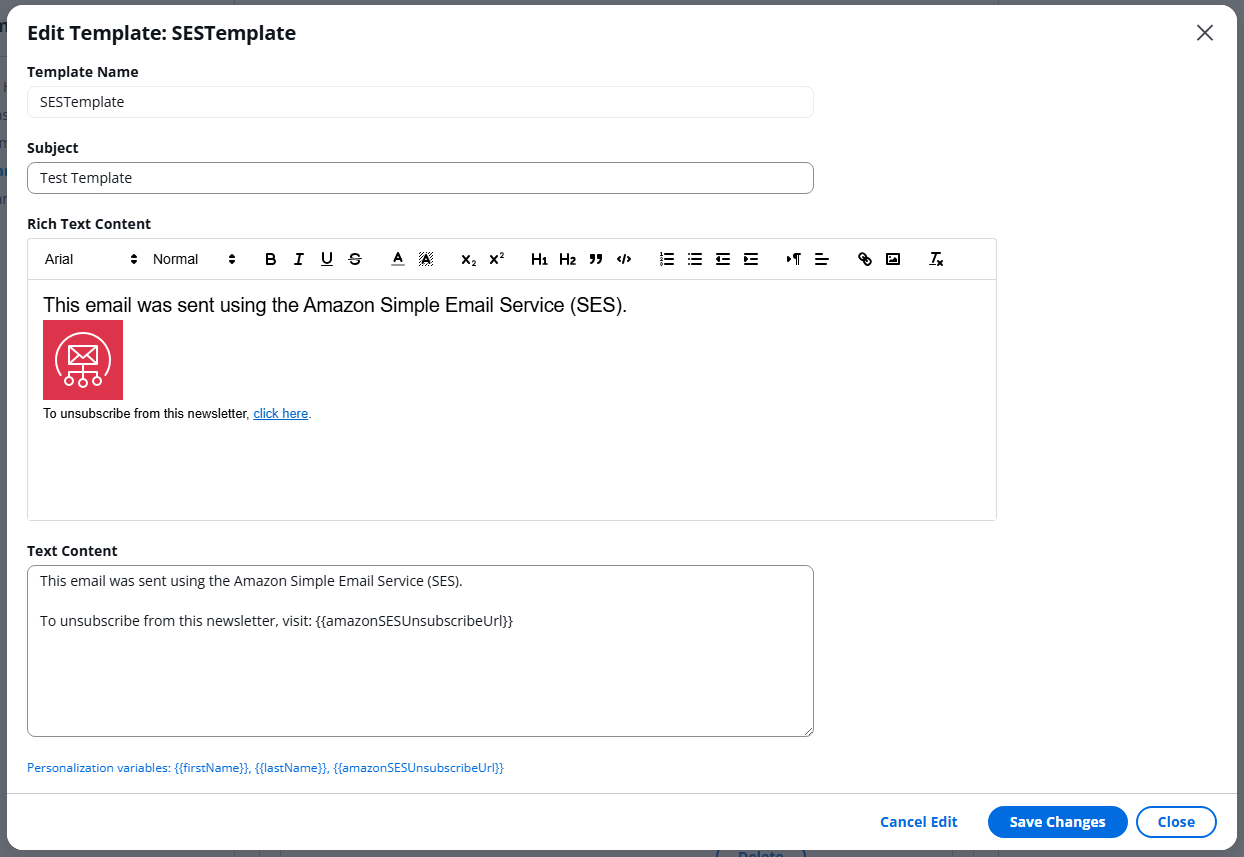
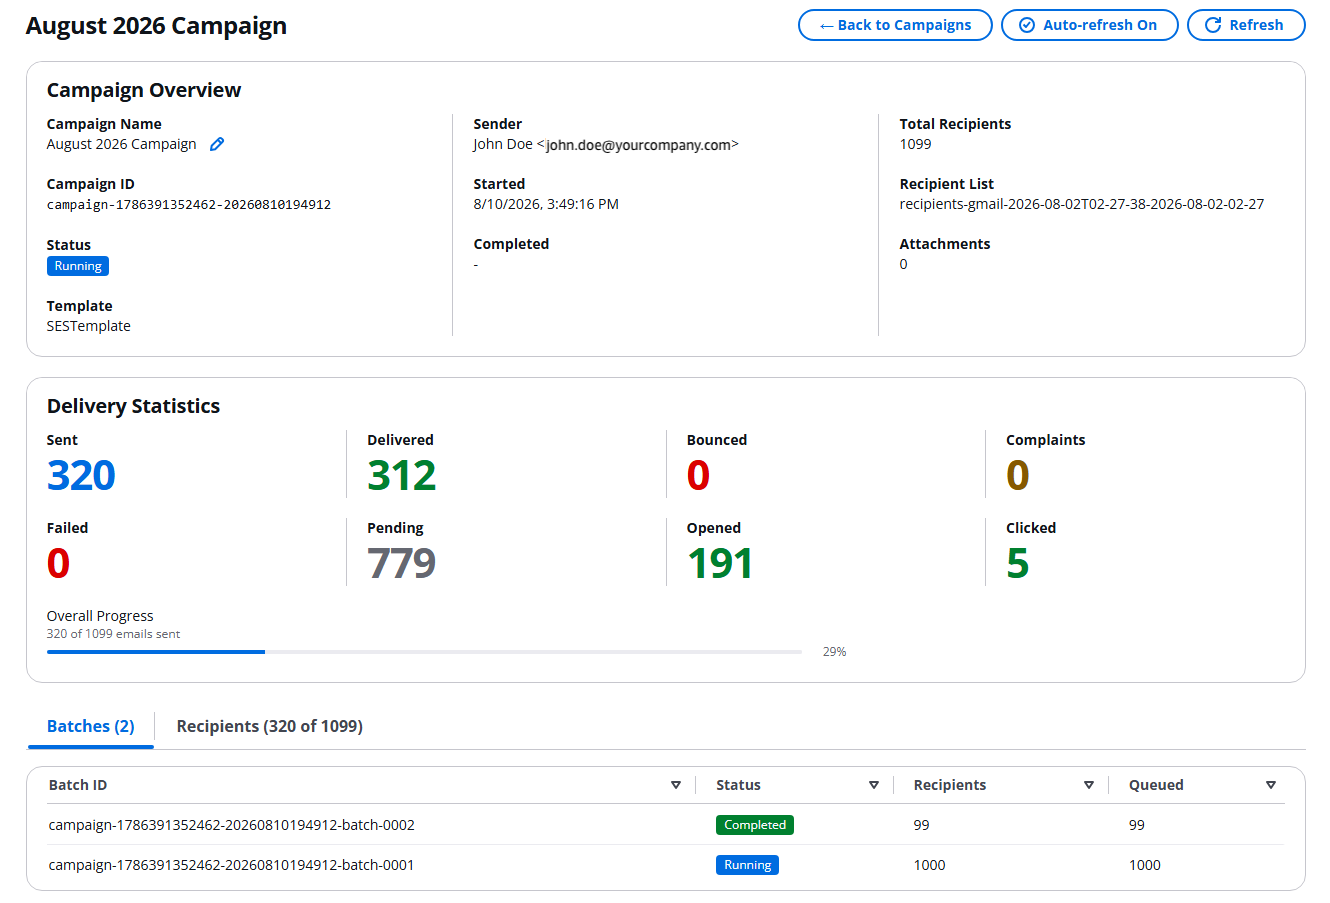
The following screenshots show the campaign interface, the template creation interface, and the campaign monitoring interface.

Email template creation interface of the mass email application

Figure 3: Email template creation interface

Mass email campaign interface of the application

Figure 4: Mass email campaign interface

Campaign monitoring interface showing the delivery status of a mass email campaign

Figure 5: Campaign monitoring interface

  1. Request processing – Each user action triggers a secure request through Amazon API Gateway to AWS Lambda functions, which then coordinate with our backend processing system.

From the user’s perspective, the experience is similar to using any standard email platform, with the added capability of handling campaigns at scale. This interface helps marketing teams, customer success managers, and business operations staff create and launch email campaigns directly through their browser, without needing to understand complex email protocols.

Backend architecture

After a user initiates an email campaign, our backend orchestrates a series of steps to facilitate reliable, large-scale email delivery. Let’s follow how an email campaign flows through the system:

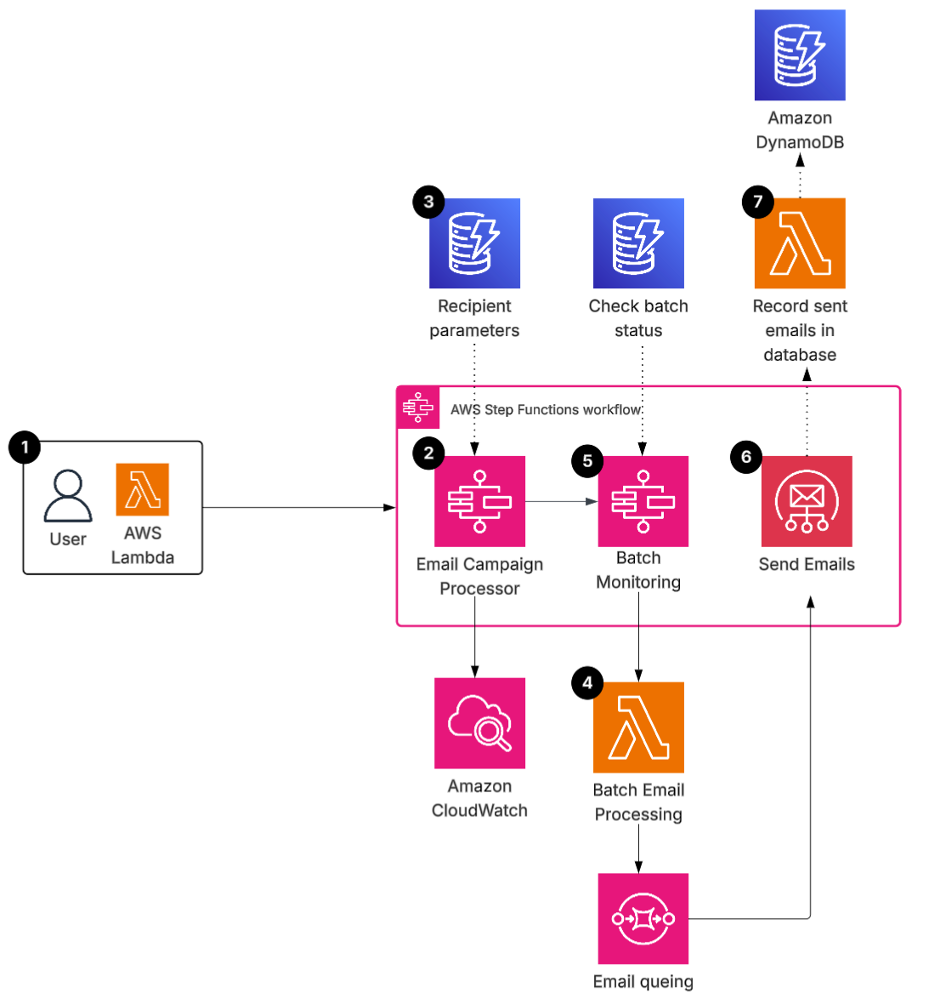
Backend architecture: Step Functions orchestrates batching, Lambda sends email through Amazon SES, and DynamoDB logs delivery attempts

Figure 6: Backend architecture of the SES email application

As shown in the preceding figure, the backend processes email campaigns through the following steps:

  1. Email campaign processor – When a user creates a new campaign through the GUI, a Lambda function processes the initial request, taking the user’s selected email template and campaign parameters. The function then triggers an AWS Step Functions workflow.
  2. Workflow orchestration – The Step Functions workflow acts as the conductor and coordinates the entire email sending process. It initializes the campaign, sets up necessary configurations, and organizes the campaign into manageable batches.
  3. Recipient processing – Before sending email, the Step Functions workflow retrieves recipient information, including the recipient’s name and email address, from DynamoDB and checks it for accurate delivery details.
  4. Batch email processing – The Step Functions workflow begins organizing the email into manageable batches. The workflow queues these batches in Amazon Simple Queue Service (Amazon SQS), preparing them for processing.
  5. Batch monitoring – As batches move through the system, Step Functions actively monitors their progress, tracking the status of each batch throughout the sending process.
  6. Email sending – When SQS receives a message, it invokes a Lambda function that sends the email to Amazon SES for delivery. The function logs each delivery attempt in DynamoDB, with failed deliveries automatically returning to the SQS queue for retry attempts. It also records successful deliveries to support idempotency and prevent duplicate sends.
  7. Record management – DynamoDB stores an audit trail that tracks both successful and failed delivery attempts, providing detailed logs to support reporting, campaign performance assessments, and compliance efforts.

Using these AWS services, the solution automatically scales from sending a few email to millions without manual intervention or infrastructure provisioning. You pay only for what you use, with no idle server costs. To demonstrate the cost-effectiveness of this architecture: sending 10,000 email costs approximately USD $4, including all AWS service charges. For current pricing details, refer to Amazon SES pricing.

To deploy this solution in your AWS account, refer to the source code on GitHub.

Conclusion

In this post, we explored the architecture of a scalable email sending solution using Amazon SES and other AWS serverless services. This architecture removes the complexity of traditional email infrastructure while providing capabilities for handling large-scale email campaigns. Whether you’re looking to modernize your existing email infrastructure or stand up a new solution, this serverless approach offers the ideal combination of streamlined design, scalability, and cost-effectiveness.

Additional resources


About the authors

MAPS: Netflix’s Multimodal Asset Personalization at Scale

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/maps-netflixs-multimodal-asset-personalization-at-scale-32f96320785e

By Emma Yanyang Kong, Aditya Deshpande, Asad Abbasi, Bowei Yan, David Fagnan, Ashish Rastogi, Dhaval Patel, Ray Zhang

Introduction

The Netflix experience is a journey of discovery. Every visual cue, from the artwork on a title to the video previews that autoplay while you browse, is there to connect you with a story you will love. We call these visual cues assets, and choosing the right one for each member is a personalization problem of its own. But which image or video preview of Squid Game should we show you? And what do we do right after a title launches, when there’s far too little interaction data to know which asset we should recommend to each member?

For years, our models answered the first question well and the second poorly. They learned which assets members interacted with, but treated every asset as an opaque ID, blind to what was actually in the artwork or video preview. Right after a title launched, its assets had no history, so we dialed up exploration on its assets to gather interaction data, and otherwise fell back to popularity heuristics that ignore your taste. Only once enough interactions had piled up could personalization take over. This is the classic cold-start problem.

This post shares how multimodal embeddings let our models see and hear the assets they recommend, so personalization can kick in far sooner, close to a title’s launch. Because a new asset arrives with its embedding the model already understands, that embedding carries member taste signals from related assets immediately. Consequently, the model needs far less interaction history before it can personalize. We cover three production systems, artwork personalization, query-aware artwork ranking, and video preview personalization, plus a cheap trick for choosing new embeddings before committing to full end-to-end integration and A/B testing.

Artwork Personalization

A single image is often a member’s first touchpoint with a title, so we create a diverse set of artworks for each title to appeal to different member tastes. We already use personalized artwork based on members’ interaction histories, but this approach breaks down for newer titles and their assets, where there is little or no behavioral data to learn from.

Making the Model See the Artwork

Our solution is to let the model “look” at the picture. We encode each artwork with CLIP, a pretrained image-text embedding model, and fold the result into how the model represents that asset, concatenating the per-asset CLIP image embedding, a 768-dimensional vector, with the asset’s learned ID embedding to give an asset representation:

e_id(a) is the asset’s learned ID embedding, and e_a is its CLIP image embedding. The two are concatenated and passed through an MLP layer to give h_a, the representation the model scores against a member.

This single change transforms how the model handles a brand-new artwork. Instead of treating it as an unseen ID, the model now receives a CLIP embedding the moment the asset is created. That allows a member’s preferences over visual themes, talent, and color palettes to be applied immediately, long before the asset accumulates any interactions of its own. Because those preferences are expressed in image-embedding space rather than tied to specific asset IDs, they transfer seamlessly across titles. If you consistently engage with artwork featuring a particular comedian, the model can carry that signal to their new title and prioritize the asset that places them front and center, even if it has never shown you that exact image before, as in the figure below. In this way, cold-start shifts from being a blind spot to something the embedding space already has an informed opinion about.

Knowledge transfer through CLIP embeddings. A member who has interacted with a comedian’s past stand-up artwork (left) leads the model to favor the new-title asset that features that comedian prominently (green check) over one that does not, even though it has never seen that specific image before.

From Five Models to One

That shift, from scoring an asset by the ID it happens to carry to scoring it by what the image actually contains, powers a second big win, model consolidation. Each title’s artwork spans multiple canvases with different croppings (billboard, vertical-box, horizontal-panel, short-panel, landscape-panel), and historically we trained a separate model per canvas, since an ID-based model has no way to know that the cropped and resized renderings of one scene are related, so signal could not flow between canvases and each faced its own cold-start.

CLIP embeddings break that barrier. Because they are largely invariant to crop, resize, and aspect ratio, those near-identical renderings map to nearly the same vector, as the figure further below shows. A single unified model can therefore pool interaction signal across every canvas, so a member’s affinity learned on a high-traffic canvas immediately informs the artwork we pick on a sparse one. The result is one model in place of five, with the largest gains on the canvases that have the least interaction data.

One source image, many canvases. The same Running Point artwork is cropped and resized across billboard, TV, mobile, and out-of-home placements, each with a different asset ID. Because CLIP embeddings barely change under crop and resize, a single unified model can personalize all of them.

Mixing Five Canvases of Training Data

Consolidation introduced a challenge that the per-canvas models never faced: how to effectively mix data across disparate canvases? The canvases differ widely in impression volume, and the interactions they log are not all worth the same to a member’s long-term experience. Training on pooled raw counts would let the highest-volume canvas and the most frequent interaction types dominate, so the low-data canvases we were trying to help would benefit least. Hand-tuning a weight per canvas would just trade that problem for a set of arbitrary hyperparameters and endless online sweeps to tune them.

Instead we use reward-based weighting, building on Netflix’s long-term reward modeling. Each training example is weighted by the long-term reward score attached to its interaction type:

a_ti is a training example, a positive interaction on asset i of title t. Its weight is set by the interaction type e observed on it, scored by ρ, that type’s long-term reward.

where e(·) is the type of the observed positive interaction and ρ is that type’s long-term reward score. Because interaction types are not distributed evenly across canvases, weighting by long-term value rebalances the canvas mixture on its own, with no weight set by hand. A canvas contributes in proportion to the long-term value of the interactions it drives rather than to how many impressions it happens to get. Consolidation becomes feasible, and the unified model optimizes for long-term member satisfaction instead of whichever short-term action is most frequent.

A Note on Offline Evaluation

Every result presented here must clear two bars: an offline metric evaluation followed by a large-scale online A/B test. The offline metric is the subtle one. Judging a new model on logs from the current production policy is biased, because that policy shows some assets far more often than others. The logged rewards describe what the policy preferred, not what members would have chosen from the full candidate set, so a new model that disagrees with the logging policy looks worse than it is, because the impressions it would have picked are barely represented in the data.

We handle this with inverse propensity scoring (IPS) computed on a dedicated slice of exploration traffic. A small fraction of traffic is served by a randomized policy that samples among a title’s candidate assets from a known distribution, so the propensity of showing a given asset in a given context is logged exactly at serving time rather than estimated after the fact. Reweighting every observation by the inverse of its logged propensity gives:

where D is the exploration slice and r(x, a) is the observed reward, such as a play. Impressions that exploration made rare are upweighted accordingly, and the estimator becomes an unbiased estimate of the reward a candidate policy would have earned had we actually deployed it. Having propensities that are known by construction, rather than modeled after the fact, is in our experience the single biggest reason our offline numbers track online outcomes. We report IPS as a ratio against the production baseline, and a candidate has to win there before it gets any A/B traffic.

Combining Both Ideas Works Better

Two ideas are bundled together here, so we ablated them separately against the old five-model production system.

  • V1, image embeddings only. The five per-canvas models kept as they were, each one augmented with image embeddings.
  • V2, unified model only. A single model trained over all five canvases, but with learned ID embeddings alone and no image content.
  • V3, both together. One unified model over all five canvases, with image embeddings in its asset representation.

As the chart below shows, each idea helped exactly where we expected: on the data-starved short-panel canvas and landscape-panel canvas. V3 was the clear winner. A change inside ±1% is not significant for this offline metric, and those bars are hatched in the chart. Most of what V1 and V2 do on their own sits inside that band.

Relative offline IPS lift by canvas for the three variants, each measured against the prior per-canvas model on that same canvas. Both ideas help where interaction data is scarcest, and V3 is strongest. Hatched bars fall inside the ±1% band, where the change in the offline metric is not significant; V3 values are labeled on the plot.

In the online A/B test across all device platforms, which ran for at least four weeks, the results drew a much clearer line: Neither idea moved our online core member metrics on its own. V1 and V2 were both flat and non-significant, and only V3 won a statistically significant lift. It is what runs in production today.

The two ingredients need each other. V1 tells a per-canvas model what an asset looks like, but one sparse canvas has too few examples to teach it how to use that. V2 supplies plenty of data, but only ID-based data, which a new asset lacks. V3 has both, so mature canvases teach the shared model how CLIP embeddings map to member preference and that mapping transfers straight to the sparse ones. The effects compound rather than add, since the V3 short-panel lift (5.691%) exceeds V1 and V2 combined. The lesson is to look for a second blocking factor before concluding that content features do not help.

Cold-Start Challenge from a New UI Launch

The real test came from the product change that motivated the work. Netflix was preparing its largest TV home-screen redesign in a decade, which would make short-panel the dominant artwork canvas effectively overnight. This was a cold-start problem in its sharpest form. The canvas about to receive the most impressions had the least historical data, and waiting for short-panel interactions to accumulate would have degraded the user experience. Consolidation lets short-panel selection draw on signal pooled from every canvas, and CLIP embeddings let the unified model personalize a short-panel asset that has gathered very few interactions of its own.

We shipped V3 ahead of the launch and measured it with a month-long holdback A/B test, keeping a small control group on the prior per-canvas model. V3 absorbed the shift immediately, with statistically significant gains on both our core discovery metric and streaming hours, and larger gains than in the steady-state ablation. That stronger result is what we expected, since a sudden shift in which canvas dominates is exactly where V3 should help most.

Query-Aware Artwork Personalization

Your general taste is the right signal when browsing, but not when searching. For example, when searching for a specific actor, you want artwork that features them, even if your broader taste says otherwise. On the Netflix Search Page, the member’s intent is explicit and stated in the query, and the displayed artwork should reflect it.

The same CLIP embeddings we added for cold-start hand us this almost for free. Because CLIP projects text and images into one shared embedding space, we can measure how well a query matches a candidate artwork directly by the cosine similarity between the CLIP text embedding of the query and the CLIP image embedding of the asset. We blend that alignment term with the usual personalization score:

Here the personalization term is the score the artwork model above already produces for a member and asset, the second term compares the text embedding of the query against the image embedding of the asset, and the mixing weight α between 0 and 1 is tuned through online A/B testing. The first term is “what we think you like”; the second is “what you just asked for,” and α sets how much each matters.

Crucially, this took no extra modeling effort. The CLIP embeddings already sit in the asset representation from the artwork work above, so they carry the text-image alignment for free, and we get a query-aware ranker by adding a single similarity term at scoring time. The effect is visible in the search results themselves.

Query-aware artwork for a search for a specific actor. Each result surfaces an asset that visually features the searched actor, aligning the artwork with the member’s explicit intent.

Personalizing Video Previews via MediaFM

Video previews raise the bar over still artwork. A video preview unfolds over time, and its appeal comes as much from motion, pacing, dialogue, and soundtrack as from any single frame. Our older video preview personalization models saw none of that. Like the early artwork models, they treated each preview as an opaque ID. Our first content-aware attempt, SeqCLIP, described a video preview by its frames, encoding each with a CLIP embedding and then averaging them into one vector. That captured what a video preview looked like, but a mean of still frames still misses what it sounds like, the dialogue and music that carry so much of a preview’s tone.

To capture the rest, we turned to MediaFM, Netflix’s first in-house multimodal foundation model. Trained on 80 million shots, MediaFM fuses the following three signals per shot into a single embedding:

  • Visual: SeqCLIP
  • Audio: A pretrained speech and audio embedding model
  • Text: Captions encoded via a large-scale text model

Adopting MediaFM required no new infrastructure, since we simply integrate its shot embeddings into the asset representation, exactly as we did with CLIP embeddings for artwork.

The added modalities paid off. We evaluated both embeddings against the ID-only baseline offline with IPS and then in a five-week online A/B test across all device platforms, and both signals gave the same ordering, MediaFM > SeqCLIP > ID-only, and each step of added content awareness helped, with the gains largest on TV. Offline, both content-aware embeddings beat the ID-only baseline on IPS and MediaFM beat SeqCLIP, as the chart below shows. Online, MediaFM came out on top too, delivering a statistically significant lift in our core streaming metric over the ID-only baseline and outperforming SeqCLIP. This shows that the audio and timed-text signals, which a visual-only encoder like SeqCLIP cannot capture, add real value. We have since shipped MediaFM as the default video preview embedding across all platforms.

Relative offline IPS lift for the two content-aware video preview embeddings, each measured against the ID-only baseline at the zero rule. Adding visual content awareness helps, and adding audio and timed text on top of it helps further.

Choosing Embeddings Cheaply with a Proxy Task

New embeddings arrive constantly, but end-to-end trials are expensive, which cost data engineering, model retraining, and weeks of A/B test traffic. We couldn’t afford to run the full pipeline for every candidate, so we gated the funnel with a cheap question:

From the content embedding alone, can you predict which asset wins under a plain, unpersonalized policy?

We first select a fixed set of titles. For each title we use exploration data to find its debiased popularity winner, the asset with the highest interaction rate after we adjust for how often it was shown using its propensity score. We mark this winner with a binary label, 1 for the winner and 0 otherwise. We then train a linear probe to recover that label from the asset embedding alone, with no title, cast, or metadata, by minimizing the standard binary cross-entropy loss:

Keeping the probe linear and embedding-only is intentional, since it isolates how much of an asset’s popularity is actually encoded in the embedding. If the embedding captures the semantic drivers of popularity, a simple linear classifier should be able to identify likely winners. If it does not, the probe performs no better than random guessing, which is the baseline we score it against.

We first used the linear probe to screen and prune a broad set of candidate embeddings before modifying any production pipeline, narrowing the field to two finalists, SeqCLIP and the leading MediaFM variant. We then carried both through full offline evaluation and online A/B testing. All three signals, the linear probe accuracies, the offline IPS lifts, and the online A/B results, ranked MediaFM ahead of SeqCLIP, as the chart below shows. That alignment is why the linear probe now gates every new MediaFM version before release.

Linear probe Δaccuracy, offline IPS lift, and online A/B metric lift for the two finalists. All three agree that MediaFM beats SeqCLIP. The online panel is measured against the ID-based baseline, with its values withheld.

The Netflix Embedding Store

None of this would be practical without shared infrastructure. Every embedding in this post, CLIP for artwork, SeqCLIP and MediaFM for video previews, lives in the Netflix Embedding Store, a component of Netflix’s AI Platform that hosts dense embeddings for titles, games, member profiles and multimedia assets. A foundation model encodes raw asset content into a dense vector once, and the Embedding Store serves that vector to every downstream system, the artwork model, the query-aware ranker, the video preview model, and others, through the same interface. Crucially, it serves the exact same embeddings at training time and at online inference time, so there is no skew between what a model learns from and what it sees in production.

Its key property is that it decouples foundation-model updates from personalization-model deployments. A new embedding, or a new version of an existing one, can be registered, backfilled across the catalog, and validated entirely on its own, without touching the training or serving code of any model that consumes it. Once it is in the Embedding Store, it becomes available to every ranking and personalization model through configuration alone, no downstream code changes, no coordinated release. This is what let us swap CLIP into the artwork model, stand up the query-aware ranker on the same vectors, and roll MediaFM through the video preview model, each as an independent change rather than a cross-team migration.

Foundation-model embeddings (CLIP, SeqCLIP, MediaFM) are stored once and consumed by every downstream system: artwork, query-aware artwork, video previews, and other rankers.

What We Learned, and What’s Next

Three lessons stood out.

  1. Pretrained CLIP embeddings let us consolidate five artwork models into one while boosting performance on data-starved canvases. This benefit became especially clear when the redesigned TV home screen rolled out.
  2. For video, multimodality wins decisively. The audio and text signals that a purely visual encoder cannot access pushed MediaFM past SeqCLIP.
  3. A cheap proxy task yields big savings, efficiently pruning the candidate set before running full end-to-end experiments and online A/B tests.

Next, we aim to extend the Embedding Store toward a single shared semantic space for image, text, and video. Such a unified representation would enable cross-modal retrieval, such as matching a video preview to a search query, or a static artwork to the video preview it was derived from, as well as unified asset ranking across surface types and a more cohesive, intuitive discovery experience for members everywhere.

Acknowledgements

We thank Aneesh Vartakavi, Santiago Castro, and Avneesh Saluja for the CLIP embedding and MediaFM work that made the content-aware models described here possible, and Ratna Kavuri for the backend systems that serve multimedia personalization in production.


MAPS: Netflix’s Multimodal Asset Personalization at Scale was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Eight stable kernels with fix for a single vulnerability

Post Syndicated from jzb original https://lwn.net/Articles/1091118/

Greg Kroah-Hartman has announced the release of the 7.2.2, 7.1.12, 6.18.48, 6.12.107, 6.6.155, 6.1.186,
5.15.219, and 5.10.268 stable kernels.

Each of these contains a
single fix for a
vulnerability
(CVE-2026-80590)
that allows marking IPv4 or IPv6 fragments as GSO,
which can allow an unprivileged user to cause a kernel panic. This vulnerability
has been present since Linux 2.6.27. Users are advised to upgrade.

Build your own continuous modernization pipeline with AWS Transform custom

Post Syndicated from Janardhan Molumuri original https://aws.amazon.com/blogs/devops/build-your-own-continuous-modernization-pipeline-with-aws-transform-custom/

Introduction

Development velocity has reached new heights with AI-driven development tools and practices. Organizations are generating code faster than ever before. But that speed carries risk. Researchers Anderson, Parker, and Tan warned in MIT Sloan Management Review, “Legacy systems tend to carry hidden debt; layering AI-generated code on top of them creates additional tangled dependencies.The faster you generate code, the faster technical debt compounds — especially in brownfield environments where outdated frameworks, deprecated libraries, and undocumented services already carry years of accumulated risk.

As organizations accelerate their software development, manual or periodic processes to synchronize dependencies and update documentation no longer keep pace, and technical debt piles up faster than ever. Continuous modernization built into your pipeline enables you to maintain up-to-date dependencies and documentation across repositories on every commit, preventing future tech debt and improving AI agent accuracy and accountability.“

You can embed AI-powered code transformations directly into your CI/CD pipelines, turning modernization from a periodic project into an automated, ongoing practice. AWS gives you two ways to get there. AWS Transform – continuous modernization is the fully managed option, delivering continuous modernization automatically with no pipeline for you to build or maintain. The Do-It-Yourself (DIY) approach assembles the same practices yourself using AWS Transform custom and your existing CI/CD platform. Choose DIY when you need to fit modernization into a specific pipeline (GitHub Actions, AWS CodePipeline, Jenkins, GitLab CI, and so on), or want to customize the workflow with existing tools like Dependabot.

In this post, we cover the DIY approach on how to set up a continuous modernization pipeline using AWS Transform custom and demonstrate it in action.

The Do It Yourself (DIY) path – continuous modernization pipeline with AWS Transform custom

Sample application: instrumentShop

For this walkthrough, we use a dated Java application called instrumentShop (Figure 1) — a Java microservices application built with Spring Boot that simulates an online instrument shop to demonstrate four practices: automated dependency remediation, auto-documentation on every commit, scaling transformations across repositories, and continual learning.

Architecture overview
instrumentShop Java application architecture: a Spring Gateway routing traffic to four REST services (Agents, Instruments, Consumers, Products), with a Thymeleaf client, PostgreSQL persistence, and Hystrix circuit breaking.

Figure 1: instrumentShop Java application architecture

The instrumentShop application is a Spring Boot microservices application with a Spring Gateway (v1.5.19) routing traffic from a single HTTP/8010 entry point to four REST services: Agents, Instruments, Consumers, and Products. A Thymeleaf client provides server-side rendering, PostgreSQL 13.1 handles persistence via JDBC, and Hystrix provides circuit-breaking for inter-service calls. A ShopTester utility generates HTTP traffic for testing.

This application is a strong candidate for continuous modernization:

  • Spring Boot 1.5.19 is years past end of life and carries known CVEs
  • Hystrix has been in maintenance mode since Netflix deprecated it in 2018
  • Cross-service coordination — dependency updates must propagate across multiple microservices
  • Transitive dependency risk — PostgreSQL JDBC drivers and other transitive dependencies accumulate security advisories over time

A typical workflow for the continuous modernization pipeline is shown below (Figure 2):

  • A developer pushes code to main — GitHub Actions triggers the auto-documentation workflow, generating updated architecture docs and technical debt reports.
  • Dependabot detects a vulnerable dependency — A PR opens automatically. GitHub Actions triggers the dependency remediation workflow, runs AWS Transform custom to remediate the code, validates with tests, and pushes the result back to the PR.
  • A platform team defines a new transformation (e.g., “Upgrade Spring Boot to the latest stable release “) — The scheduled GitHub Actions workflow runs the transformation weekly in non-interactive mode across all instrumentShop microservices and other repositories in the portfolio.
  • The agent learns — Knowledge items from each execution improve future runs, reducing manual intervention over time.

AWS Transform continuous code modernization workflow
Figure 2: AWS Transform continuous code modernization workflow

Prerequisites

  • Before setting up the continuous modernization pipeline, ensure you have the following:
  • An active AWS account with permissions for AWS Transform custom
  • AWS Transform CLI installed and configured in your development environment
  • Authentication with AWS credentials configured locally and proper IAM permissions to call AWS Transform
  • Git installed for cloning sample repositories
  • GitHub Dependabot enabled on your repository for automated vulnerability detection

Continuous modernization through CI/CD in action

Continuous modernization shifts code transformation from a periodic project into an automated, pipeline-driven practice. Instead of scheduling a “modernization sprint” once a year, your CI/CD pipeline identifies and remediates technical debt on every commit, every dependency alert, and across every repository.

We implement this through four practices, each powered by AWS Transform custom running as a step in GitHub Actions workflows.

Note: This post uses GitHub Actions because the instrumentShop demo repository is built with it. The same AWS Transform CLI (atx) commands work with AWS CodePipeline, Jenkins, GitLab CI, CircleCI, or any CI/CD system that runs shell commands. Continuous modernization is a practice, not a tool choice.

Important: Every atx custom def exec invocation in this post uses the –trust-all-tools flag, which allows the agent to execute tools without interactive confirmation. This is required for non-interactive CI/CD execution. Review your organization’s security policies before enabling this flag in production pipelines.

1. Dependency analysis and remediation

GitHub Dependabot scans your repository for known vulnerabilities and generates alerts when a new vulnerability is added or your dependency graph changes—for example, when you push commits that update packages or versions. However, resolving these alerts requires more than bumping a version number. Upgrading a dependency can introduce breaking API changes, require code modifications, or demand configuration updates.

AWS Transform custom helps handle the code changes needed to resolve the alerts. It runs via a GitHub Actions workflow that triggers automatically to:

  • Fetch the list of latest Dependabot alerts
  • Run AWS Transform custom to analyze the alerts and apply code transformations
  • Run your build and test suite to validate the changes
  • Create a new pull request for each resolved alert

The workflow calls a shell script that invokes the AWS Transform CLI in headless mode with retry logic. Place this script at the root of your repository:

run_dependabot_alert_fixes.sh:

#!/usr/bin/env bash
set -euo pipefail

# -------------------------------------------------------------------
# run_dependabot_alert_fixes.sh
# Runs the Dependabot alert remediation transformation in headless mode.
# Retries up to MAX_RETRIES times on failure.
#
# Usage:
#   ./run_dependabot_alert_fixes.sh [-n <transformation-name>] [-p <path>] [-c <build-command>]
#
# Defaults:
#   -n  Remediate-Critical-GitHub-Dependabot-Alerts-Java-Maven
#   -p  .                   (current directory)
#   -c  mvn clean install   (Maven build)
# -------------------------------------------------------------------

TRANSFORMATION_NAME="Remediate-Critical-GitHub-Dependabot-Alerts-Java-Maven"
CODE_PATH="."
BUILD_CMD="mvn clean install"
MAX_RETRIES=3

while getopts "n:p:c:" opt; do
  case $opt in
    n) TRANSFORMATION_NAME="$OPTARG" ;;
    p) CODE_PATH="$OPTARG" ;;
    c) BUILD_CMD="$OPTARG" ;;
    *) echo "Usage: $0 [-n <transformation-name>] [-p <path>] [-c <build-command>]" && exit 1 ;;
  esac
done

echo "=== AWS Transform Custom ==="
echo "Transformation: $TRANSFORMATION_NAME"
echo "Code path:      $CODE_PATH"
echo "Build command:  $BUILD_CMD"
echo "============================"

attempt=1
while [ $attempt -le $MAX_RETRIES ]; do
  echo "--- Attempt $attempt of $MAX_RETRIES ---"

  if atx custom def exec \
    -n "$TRANSFORMATION_NAME" \
    -p "$CODE_PATH" \
    -c "$BUILD_CMD" \
    -x -t; then
    echo "=== Transformation completed successfully ==="
    exit 0
  fi

  echo "Attempt $attempt failed."
  attempt=$((attempt + 1))

  if [ $attempt -le $MAX_RETRIES ]; then
    echo "Retrying in 10 seconds..."
    sleep 10
  fi
done

echo "=== All $MAX_RETRIES attempts failed ==="
exit 1

This script accepts optional flags to override the transformation name (-n), code path (-p), and build command (-c). The -x flag enables non-interactive mode and -t enables --trust-all-tools, both required for CI/CD execution. On failure, it retries up to three times with a 10-second backoff.

Your CI/CD workflow must configure AWS credentials and install the AWS Transform CLI before invoking this script. With this setup, Dependabot alerts are reviewed continuously for any changes — not just a version bump, but the complete code adaptation required to make the upgrade work.

2. Auto documentation

Documentation is one of the most neglected aspects of modern software development. Documentation increases accuracy and acts as a contract between requirements and implementation. AWS Transform custom codebase analysis capability generates structured documentation covering architecture, technical debt, code metrics, and migration planning on every incremental update ensuring every Agent or human that modifies the codebase is working from a true “current state”.

By embedding this as a post-push step in your CI/CD pipeline, your documentation stays current automatically. The workflow triggers on every pull request to main, runs your build and test suite, then calls a shell script that invokes AWS Transform custom to generate documentation and commits it back to the PR branch.

Place this script at the root of your repository:

run_code_analysis.sh:

#!/usr/bin/env bash
set -euo pipefail

# -------------------------------------------------------------------
# run_code_analysis.sh
# Runs an AWS Transform custom transformation in headless mode.
# Retries up to MAX_RETRIES times on failure.
#
# Usage:
#   ./run_code_analysis.sh [-n <name>] [-p <path>] [-c <build-cmd>] [-U <pr-url>]
#
# Defaults:
#   -n  GitHub-PR-Context-Codebase-Analysis
#   -p  .                   (current directory)
#   -c  mvn clean install   (Maven build)
#   -U  (empty)             PR URL
# -------------------------------------------------------------------

TRANSFORMATION_NAME="GitHub-PR-Context-Codebase-Analysis"
CODE_PATH="."
BUILD_CMD="mvn clean install"
PR_URL=""
MAX_RETRIES=3

while getopts "n:p:c:U:" opt; do
  case $opt in
    n) TRANSFORMATION_NAME="$OPTARG" ;;
    p) CODE_PATH="$OPTARG" ;;
    c) BUILD_CMD="$OPTARG" ;;
    U) PR_URL="$OPTARG" ;;
    *) echo "Usage: $0 [-n <name>] [-p <path>] [-c <build-cmd>] [-U <pr-url>]" && exit 1 ;;
  esac
done

echo "=== AWS Transform Custom ==="
echo "Transformation: $TRANSFORMATION_NAME"
echo "Code path:      $CODE_PATH"
echo "Build command:  $BUILD_CMD"
echo "PR URL:         $PR_URL"
echo "============================"

attempt=1
while [ $attempt -le $MAX_RETRIES ]; do
  echo "--- Attempt $attempt of $MAX_RETRIES ---"

  if atx custom def exec \
    -n "$TRANSFORMATION_NAME" \
    -p "$CODE_PATH" \
    -c "$BUILD_CMD" \
    -g "additionalPlanContext=$PR_URL" \
    -x -t; then
    echo "=== Transformation completed successfully ==="
    exit 0
  fi

  echo "Attempt $attempt failed."
  attempt=$((attempt + 1))

  if [ $attempt -le $MAX_RETRIES ]; then
    echo "Retrying in 10 seconds..."
    sleep 10
  fi
done

echo "=== All $MAX_RETRIES attempts failed ==="
exit 1

This script accepts optional flags for the transformation name (-n), code path (-p), build command (-c), and PR URL (-U). Pass the PR URL to the agent via the -g flag as additionalPlanContext, giving it awareness of the pull request context when generating documentation. On failure, it retries up to three times with a 10-second backoff.

Your CI/CD workflow must configure AWS credentials and install the AWS Transform CLI before invoking this script. The workflow commits the generated documentation back to the PR branch automatically, keeping your architecture docs and technical debt reports current with every code change.

Every push now updates the documentation (Figures 3 and 4) — reducing knowledge silos and preserving institutional knowledge.

A GitHub pull request triggering the auto-documentation workflow.

Figure 3: PR triggering auto-documentation

Generated documentation output showing architecture and technical debt reports.

Figure 4 – Generated documentation output

3. Scale across repositories

For organizations with hundreds of microservices, transforming one repository at a time doesn’t scale. AWS Transform custom non-interactive mode combined with GitHub Actions matrix strategy allows you to orchestrate transformations across your entire portfolio in parallel. You can run them on demand or on a recurring schedule, so modernization runs as a continuous practice rather than a one-time project.

# .github/workflows/scale-modernization.yml
name: Scale Modernization
on:
  schedule:
    - cron: '0 6 * * 1'
  workflow_dispatch:

jobs:
  transform-repos:
    runs-on: ubuntu-latest
    strategy:
      matrix:
        repo:
          - magnefique-studios/instrumentShop
          - magnefique-studios/orderService
          - magnefique-studios/paymentGateway
    steps:
      - name: Checkout ${{ matrix.repo }}
        uses: actions/checkout@v4
        with:
          repository: ${{ matrix.repo }}
          token: ${{ secrets.GH_PAT }}

      - name: Configure AWS credentials
        uses: aws-actions/configure-aws-credentials@v4
        with:
          role-to-assume: ${{ secrets.AWS_ROLE_ARN }}
          aws-region: us-east-1

      - name: Install ATX CLI
        run: curl -fsSL https://transform-cli.awsstatic.com/install.sh | bash

      - name: Run transformation
        run: |
          atx custom def exec \
            --transformation-name "spring-boot-3-upgrade" \
            --code-repository-path "." \
            --build-command "mvn clean install" \
            --non-interactive \
            --trust-all-tools

Tip: GitHub Actions matrix strategy runs each repository in parallel automatically — no separate orchestration layer needed. For larger portfolios, you can also wrap this in AWS Batch or AWS Fargate for large-scale parallel execution. The AWS Transform web console tracks progress across all repositories in a single view.

4. Continual learning

Each time AWS Transform custom completes a transformation, a memory agent scans the full execution trajectory and extracts lessons. Lessons include patterns that the agent learned, decisions that the agent made during planning, and feedback you provide during execution. AWS Transform custom automatically attaches these lessons to your transformation definition, which improves accuracy in subsequent runs.

AWS Transform custom applies lessons automatically, and each lesson belongs to a category that groups related lessons for review. You can browse and archive any lesson you do not want AWS Transform custom to apply to future runs.This keeps a human in the loop on what the agent “remembers” which matters when the same transformation runs across many repositories with different conventions.

In practice, this means your “Spring Boot 3 Upgrade” transformation gets sharper with each execution. The first repository surfaces the edge cases; once you review the resulting lessons and archive the ones that do not fit, subsequent runs handle those edge cases without intervention.

For production use, you can combine these practices into a single workflow file:

Note: The individual workflows shown in Practices 1–3 are presented separately for clarity. Combine them into a single workflow file as shown here, or keep them as separate workflow files depending on your team’s preference.

# .github/workflows/continuous-modernization.yml
name: Continuous Modernization
on:
  push:
    branches: [main]
  pull_request:
    types: [opened]
  schedule:
    - cron: '0 6 * * 1'

jobs:
  dependency-remediation:
    if: github.actor == 'dependabot[bot]'
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with:
          ref: ${{ github.head_ref }}
      - name: Configure AWS credentials
        uses: aws-actions/configure-aws-credentials@v4
        with:
          role-to-assume: ${{ secrets.AWS_ROLE_ARN }}
          aws-region: us-east-1
      - name: Install ATX CLI
        run: curl -fsSL https://transform-cli.awsstatic.com/install.sh | bash
      - name: Remediate dependency changes
        run: |
          atx custom def exec \
            --transformation-name "dependency-remediation" \
            --code-repository-path "." \
            --build-command "mvn clean install" \
            --non-interactive \
            --trust-all-tools

  auto-documentation:
    if: github.event_name == 'push'
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - name: Configure AWS credentials
        uses: aws-actions/configure-aws-credentials@v4
        with:
          role-to-assume: ${{ secrets.AWS_ROLE_ARN }}
          aws-region: us-east-1
      - name: Install ATX CLI
        run: curl -fsSL https://transform-cli.awsstatic.com/install.sh | bash
      - name: Generate documentation
        run: |
          atx custom def exec \
            --transformation-name "codebase-documentation" \
            --code-repository-path "." \
            --build-command "echo 'docs-only'" \
            --non-interactive \
            --trust-all-tools

  weekly-modernization:
    if: github.event_name == 'schedule'
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - name: Configure AWS credentials
        uses: aws-actions/configure-aws-credentials@v4
        with:
          role-to-assume: ${{ secrets.AWS_ROLE_ARN }}
          aws-region: us-east-1
      - name: Install ATX CLI
        run: curl -fsSL https://transform-cli.awsstatic.com/install.sh | bash
      - name: Run modernization scan
        run: |
          atx custom def exec \
            --transformation-name "tech-debt-analysis" \
            --code-repository-path "." \
            --build-command "mvn clean install" \
            --non-interactive \
            --trust-all-tools

Conclusion

Continuous modernization moves code transformation out of periodic sprints and into your CI/CD pipeline. By combining GitHub Dependabot’s vulnerability detection with AWS Transform custom agent, orchestrated through GitHub Actions, you can:

  • Remediate dependency vulnerabilities automatically — beyond version bumps to full code adaptation
  • Keep documentation current with every commit, preserving institutional knowledge
  • Scale transformations across hundreds of repositories with consistent quality
  • Improve continuously as the agent accumulates knowledge items from each execution

The instrumentShop sample application demonstrates that even a moderately complex microservices architecture — with end-of-life Spring Boot versions, deprecated libraries like Hystrix, and multiple interconnected services — can be continuously modernized without dedicated modernization sprints.

Ready to get started? This post walked through the do-it-yourself path with AWS Transform custom. If you would rather have continuous modernization delivered as a fully managed service, explore AWS Transform continuous modernization. Either way, visit the AWS Transform documentation to start your continuous modernization journey.

Janardhan Molumuri

Janardhan Molumuri is a Principal Technical Leader at AWS with over two decades of engineering leadership experience, advising customers on cloud and AI Adoption strategies and emerging technologies including generative AI. He has passion for thought leadership, speaking, writing, and enjoys exploring technology trends to solve problems at scale.

Maxine Rosa

Maxine Rosa is a Sr World Wide Generative AI Specialist at AWS focused on developer tooling including AWS Transform and Kiro. With a background in Software Engineering, Solution Engineering and Go-to-Market strategy, she helps AWS customers adopt Generative AI tooling into their current Software Development Lifecycle.

Kola Akinnibi

Kola Akinnibi is an Associate Solutions Architect at AWS focused on observability, partnering with ISVs and large enterprises to bring end-to-end monitoring to AI agents and modern applications. He helps customers design observability solutions that scale, and has a passion for sharing technical content.

Renuka Krishnan

Renuka Krishnan is a Senior Specialist Solutions Architect at AWS, specializing in code modernization using agentic AI and AWS services. She has over 15 years of experience architecting and implementing solutions, and works with customers to accelerate application development and modernization through AI-powered solutions.

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Generative AI initiatives focused on Amazon Q Developer, Kiro, and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

Security updates for Friday

Post Syndicated from jzb original https://lwn.net/Articles/1091117/

Security updates have been issued by AlmaLinux (assertj-core, golang, httpd, kernel, and libxml2), Debian (chromium and suricata-update), Fedora (rust-h2), Mageia (avahi and python-django), Oracle (kernel and mingw-openssl), SUSE (c-ares-devel, dracut, gh, gstreamer-plugins-bad, java-11-openjdk, liboqs, librest0_7, openssl, openssl-3, pcp, python313-mistune, python36-pip, qt6-svg, rmt-server, rsync, suseconnect-ng, texlive, tor, wicked, and xmlrpc-c), and Ubuntu (linux-azure, linux-azure-4.15, linux-azure-fips, linux-azure-6.8, linux-ibm, linux-ibm-6.8, linux-oracle-6.8, linux-raspi,
linux-raspi-realtime, linux-azure-fde-5.15, linux-fips, linux-gke, linux-gcp-fips, opencryptoki, and pam).

BotBase for Operators: A clearer path to joining Cloudflare’s directory of bots and agents

Post Syndicated from Julian Laxman original https://blog.cloudflare.com/botbase-for-operators/

Last month, on our second Content Independence Day, we announced a couple of features designed to give website owners more visibility and control over automated traffic: BotBase added a searchable directory of known bots to the Cloudflare dashboard, while Business Insights helped owners understand how crawlers interact with their content. We know that the ecosystem of bots is vast, making it all the more important for site owners to be able to manage bot traffic sustainably.

But this ecosystem goes both ways. While website owners need to decide which automated traffic they allow, bot operators need a clear way to identify themselves, explain what their bots do, and keep that information current. BotBase works best when both sides can participate.

When we launched BotBase, we said we would build tools to bring bot operators into this ecosystem. Until now, their experience largely ended at submission. After pressing submit, an operator had no easy way to check the submission's status, understand why it was rejected, or update an existing entry. Today, we start to change that with the launch of BotBase for Operators, tackling what bot operators need first: transparency.

A new home for bot submissions

Imagine you’re a bot operator looking to submit your bot to BotBase. Where on the dashboard would you look for such a submission form? Previously, the form lived under Manage Account → Configurations, which tied the bot clearly to your account, but didn’t acknowledge its connection to the bots ecosystem.

Starting today, the bot submission experience has a home next to the rest of your bot and trust tools: Protect & Connect → Application Security → BotBase (new!). All customers can access this today directly from the Cloudflare dashboard.

Here, we’ve split BotBase for Operators by use case:

  • Bots directory — browse, search, and filter the bots Cloudflare already tracks (the same catalogue you can explore on Cloudflare Radar).
  • Submission form — submit a new bot.
  • Submission history — track everything you have submitted.

Finding BotBase solves the "where" problem. The "what happens next" problem is the one that we’ve heard is deeply important to bot operators, so we’ll cover that in the rest of this post.

See where your submission stands

We spoke to many bot operators, and the resounding feedback was this: submitting a bot feels like a black box. You fill in the form, press submit, and wait, with no way to tell whether anything happened next.

Now, the Submission history tab shows every bot submitted from your account, each with a clear status:

  • Waiting for review — we have received your submission and it is in our queue.
  • Accepted — we have reviewed it and your bot is now tracked in the directory.
  • Rejected — something in the submission needs to change. We tell you why, with steps you can act on, so you can fix it and resubmit.

Open any submission to see its full details. If it was rejected, you will see the reason why. If it was accepted but we adjusted how your bot is classified, you will see what we changed.

Previously, operators would need to email support just to ask whether their bot got reviewed or to check on their submission's progress. That's exactly the gap we’re closing with this new tab.

Today, the submission form is no longer a black box. Every operator can now view the record of every bot they've submitted starting from today’s launch, with a status you can check anytime. We also provide a way to filter “My bots,” from the Bots directory screen, so you can see all bots that have been submitted under the account with which you’re currently logged in.

Keep your bot's information up to date

A bot's identification details can change over time. You might redesign your website and end up hosting your IP list at a new endpoint. Or you might move from an IP allowlist to signing your traffic with Web Bot Auth, and need your entry to match. Before today, the only way to reflect either change was to fill out the whole form again and submit a brand-new entry. Now, you can edit a submission you have already made.

You can also cancel a submission that is still waiting for review.

We encourage every operator to keep their bot's information current. Accurate details are a key component of how a bot earns and keeps Verified status, which increasingly determines whether sites across Cloudflare's network can easily allow it based on its behavior. Of course, it is ultimately up to the individual site owner to decide what traffic is allowed and what is not. 

A submission form built on an updated, pragmatic taxonomy

Picture a bot. Maybe it only crawls pages to build a search index. Maybe it also acts on a user's behalf, or pulls in data for something else entirely. How it uses what it reads matters just as much as what it does. 

The new intake form asks you to describe your bot the way it actually behaves. It follows the same behavior and content use model we introduced on July 1, so instead of squeezing your bot into a single label, you now tell us three things.

First, what your bot does. Maybe it only does one thing, like indexing pages for search. Maybe it's an agent acting on a user's behalf, or it collects data, trains models, or supports SEO tools. You can select every behavior that applies, not just the closest match.

Second, how it uses what it reads. A crawler that skims a page for a search snippet is not the same as one that stores that page to train a model. You tell us the level of content use your bot needs, using the same Content Signals model website owners already use to set their own rules. For example, a site's robots.txt might read Content-Signal: search=yes, ai-train=no, use=reference, telling every crawler it's fine to index the page for search and keep a reference, but not to train a model on it. Your bot's content-use declaration is what gets checked against exactly that kind of preference.

Third, who's actually running it. If you operate your bot yourself, straight from your own infrastructure, like a search engine crawling the web to build its own index, that's direct. If you run a platform other companies build on, carrying their traffic without being the one who decided to send it, that's an intermediary. Picture a general-purpose AI assistant fetching a page because someone typed a question into a different company's app built on that assistant's API: the assistant operator runs the infrastructure, but it was someone else's product that decided to send the request. (You can read more about these classifications here.)

That's the full picture: what your bot does, how it treats what it reads, and who's behind it, described as it actually is instead of squeezed into one label. The clearer that picture, the more accurately website owners can decide how to treat your bot.

Faster, more consistent review

Operators also asked for faster reviews. We hear you on this, too.

The number of new bots submitted each year has grown sharply — increasing about 7 times in volume since 2023 — and reviewing every one of them by hand doesn't scale at that pace. Until now, every submission followed the same fully manual path: someone on our team checks it against an internal rubric and makes a judgment call. That kind of review is thorough, but it doesn't scale. 

We rebuilt that process to run automatically. Your bot runs through a series of checks — is it a duplicate of one we already track, is your user-agent pattern specific enough to identify your bot without overlapping one that's already registered, and, most importantly, does your claimed verification method actually hold up? We fetch your IP list, confirm your reverse DNS, or validate your Web Bot Auth signature automatically, instead of a person doing it by hand. If everything checks out, your bot can be tracked right away. If something needs a closer look, it's routed to our team with the specific reason already flagged, instead of landing as a blank entry in a queue.

For operators, that means most submissions move faster than before.

Submit your bot today

To join hundreds of bots in BotBase who declare their behavior and content use, and be part of an ecosystem where website owners and bot operators can coexist:

  1. Go to Protect & Connect → Application Security → BotBase in the Cloudflare dashboard.
  2. Open the Submission form and declare your bot: who operates it, what it does, how it uses content, and how it proves its identity.
  3. Submit. Your submission appears in Submission history as Waiting for review.

What's next

This launch is about visibility; there's more coming. Here are our guiding goals:

  • Visibility, targeted by this launch. This gives operators the ability to see, understand, and edit submissions.
  • Ownership and observability, being targeted soon. This gives operators the ability to claim bot ownership, manage its live directory entry, and better understand how websites are treating their bot.
  • Conversation, a longer-term goal. This would open a more sustainable way for bot operators to ask websites to be let in if they can show they provide value rather than harm. 

Our vision is to keep expanding BotBase so operators can understand exactly how their bot is treated and get guidance on how to crawl the web more politely, turning a one-way submission into an ongoing relationship.

BotBase started as a directory for website owners. It is becoming a place where bot operators take part in the ecosystem, understand where they stand, and keep their information accurate. If you run a bot, submit it and tell us what you need next. We are building the operator side alongside the operators who use it.

AI Doesn’t Mean the End of Mathematics—at Least Not Yet

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/ai-doesnt-mean-the-end-of-mathematics-at-least-not-yet.html

This essay was written with Kasra Rafi, and originally appeared in The Guardian.

Earlier this month, about 40 top mathematicians gathered at OpenAI’s offices to discuss the future of their profession. The meeting was off-the-record, but if recent articles by mathematicians are any guide, it was mostly pretty glum. People fear for their jobs, their careers and the work they love.

We think the contrary view is more likely, at least in the short-term. AI models are nowhere near as capable as experienced academic mathematicians.

This isn’t to say that AIs aren’t producing stunning mathematical results at the level of PhD researchers. In mid-May, OpenAI announced that its frontier AI model disproved the unit distance conjecture, a famous 80-year-old problem in discrete geometry. In July, Anthropic’s published two AI-derived results in academic cryptanalysis. Earlier this month, OpenAI published 10 new mathematical results from its latest AI model. And Anthropic published Claude’s attempt to prove the century-and-a-half-old Riemann hypothesis.

These results are both a vivid demonstration of the amazing capabilities of frontier AI in 2026 and an illustration of their limitations. In general, these AI-powered advances in mathematics fall into one of two categories. Some are counterexamples to mathematical statements that people had been trying to prove. Others are novel applications of known techniques to existing problems that human experts either did not know or did not think of using.

The counterexample to the Jacobian conjecture is the most notable example of the first kind. Once it had been found, checking it was quick and straightforward. The difficult part was finding it among a large number of possibilities. The AI seems to have combined some sort of intuition acquired through machine learning with extensive computational search, in order to find the right example.

An example of the second kind is the unit-distance conjecture. It was motivated by an elegant construction, and most mathematicians expected it to be essentially optimal—so they generally tried to prove rather than disprove it. The counterexample brings in ideas from elsewhere in mathematics: algebraic number theory. If an expert with that background deliberately set out to find a counterexample, they would probably have succeeded. But there was no reason for someone with precisely that expertise to focus on this problem. Because of its scope, AIs don’t have those same limitations.

These results are relatively low-hanging fruit for AI; none of them required developing an extensive new theory. This does not make the discoveries trivial, or the AI’s achievements less impressive. Choosing the right direction, and recognizing an unexpected connection between subjects, are themselves forms of creativity. They are the same sorts of capabilities that led to AIs playing the game of Go at the grandmaster level, or doing Nobel-prize level chemistry in the area of protein folding.

What we have not yet seen is an AI developing a substantial new conceptual framework in order to solve a mathematical problem. Much of mathematics proceeds by identifying the objects that are truly central to a question and then developing a theory that helps us understand them. Current AIs are very strong at searching and recombining existing ideas, but they are weak at building any deep and sustained new theory.

This speaks to a more general limitation of current AI systems. They are creative in the sense that they can recombine existing ideas in novel ways. But they are not creative in others: they have not yet developed conceptually new theories or structures. And while they have larger working memories than humans do, know more about more different things than any particular human does, and can process information faster than humans, can, true novelty is still largely beyond their reach.

Of course, that distinction may not survive for very long. Predictions are notoriously hard, especially about the future of AI. None of these mathematical capabilities were explicitly designed for, or planned. They’re all emergent properties of increasingly capable AI models. We are both confident that someday we will see AI models that are capable of the type of creativity required to do novel mathematics. Will that be in a few months, a few years or a few decades? Of course we don’t know, but our guess is sooner rather than later.

PaperCut NG/MF Critical Zero-Day Exploited in the Wild

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-papercut-ng-mf-critical-zero-day-exploited-in-the-wild

Overview

On August 27, 2026, PaperCut Software published an urgent security advisory stating that it is investigating active exploitation of a vulnerability affecting PaperCut NG and PaperCut MF. PaperCut has confirmed customer incidents and is treating the issue as a security emergency. At the time of writing, the vulnerability has not been assigned a CVE identifier, and PaperCut has not publicly disclosed a CVSS score, vulnerability class, authentication requirements, or the technical details of the exploit path.

PaperCut NG and PaperCut MF are print management platforms commonly deployed within enterprise, education, and other organizational environments. Because the PaperCut Application Server provides web-accessible administrative and application functionality, organizations with servers exposed to the public internet should prioritize remediation and access restriction.

PaperCut stated in its advisory that information supplied by a university customer’s security team and digital forensics and incident response team enabled its security response team to reproduce the vulnerability in PaperCut NG and PaperCut MF. On August 28, 2026 at 02:10 AEST, PaperCut released emergency patches for PaperCut NG and PaperCut MF versions 25 and 26.

PaperCut has been targeted in the past; in 2023, CVE-2023-27350 was broadly exploited in the wild by multiple threat-actor groups, including ransomware operators. This prior history increases the urgency organizations should address this new zero-day with.

PaperCut currently considers all versions of PaperCut NG and PaperCut MF potentially impacted. Customers operating internet-accessible PaperCut Application Servers should take immediate action even if no suspicious activity has been observed.

Technical overview

The vulnerability is an authentication bypass that lets attackers invoke privileged PaperCut components. This can be leveraged to reconfigure an external database lookup. When this lookup is triggered, malicious SQL can be executed, resulting in remote code execution.

PaperCut uses the Apache Tapestry framework, whose “complex direct” request format can identify one page to display and a different page containing the component to execute. PaperCut validates access only to the displayed page. By selecting either the public Error page or Exception page for display, an attacker can bypass authentication while invoking administrative components belonging to ConfigEditor or UserList.

The attack uses HTTP POST requests to the following URIs (Note that the path segment with the value 1 shown below can be any value for this path segment, and the Error path segment may also be the Exception path segment):

/app?service=direct/1/Error/ConfigEditor/quickFindForm
/app?service=direct/1/Error/ConfigEditor/$Form
/app?service=direct/1/Error/UserList/$QuickFind.$Form

The first two URIs provide unauthenticated access to PaperCut’s configuration editor. The third can invoke a user or card search that triggers the configured external database lookup.

An attacker first uses the ConfigEditor requests to modify four external user-lookup settings:

user-lookup.db-driver
user-lookup.db-url
user-lookup.id-to-username-sql
user-lookup.enabled

These settings normally allow administrators to connect PaperCut to an external card database. After bypassing authentication, however, the attacker can configure them with a malicious JDBC connection and a malicious SQL statement.

By leveraging PaperCut’s bundled Apache Derby database driver and supplying a Derby CALL statement that activates its foreignViews feature, Derby opens an attacker-controlled H2 JDBC URL. H2 processes an inline INIT statement that creates a JavaScript-backed database trigger. PaperCut includes the Nashorn JavaScript engine, allowing that trigger to start an operating-system process. However it is expected that other mechanisms to execute an arbitrary command can also be used instead of Nashorn. Finally, the attacker submits a search through the forged UserList request. This activates the external lookup and executes the malicious SQL.

Mitigation guidance

Organizations running PaperCut NG or PaperCut MF should prioritize patching on an emergency basis, particularly where the PaperCut Application Server is accessible from the public internet.

PaperCut has released emergency patches for PaperCut NG and PaperCut MF versions 25 and 26. 

The vendor notes that these builds have not undergone their normal release process and are intended as emergency fixes for customers with public-facing servers that cannot otherwise sufficiently mitigate exposure. An emergency patch for version 24 is still in development at the time of the vendor’s latest update.

PaperCut recommends that administrators immediately restrict web access to trusted IP addresses only, such as internal corporate network ranges. Firewall rules, network access controls, reverse-proxy restrictions, or equivalent measures should be used to prevent untrusted internet hosts from reaching PaperCut web interfaces.

Please read the PaperCut security advisory for the latest remediation guidance, updated indicators of compromise, and additional release information.

Artifacts/Evidence Sources and IOCs

For detection and forensic analysis, PaperCut has identified several preliminary artifacts and evidence sources that may indicate compromise.

  • Application activity: Alerts from intrusion-detection, endpoint-security, or network-monitoring products involving the PaperCut Application Server, particularly suspicious post-exploitation activity associated with pc-app.exe.

  • Log integrity: Missing, unexpectedly truncated, or deleted PaperCut server.log files.

  • PaperCut server.log entries:

    • ERROR No suitable driver found for jdbc:no:x

    • ERROR DatabaseUtils – Database error looking up cardID: VALUES CAST

PaperCut has not yet published validated network-based indicators such as malicious IP addresses, domains, or URLs.

The vendor specifically warns that the absence of these indicators should not be interpreted as evidence that a system has not been affected.

Rapid7 customers

Exposure Command, InsightVM, and Nexpose

Exposure Command, InsightVM, and Nexpose customers can assess exposure to this new PaperCut zero-day, with an authenticated vulnerability check expected to be available in the August 28 (today’s) content release.

Updates

  • August 28, 2026: Initial publication.

Озеленяването при нови строежи – два завършени анти-примера

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/ozelenyavane-2/

В предишната част от материала описах какви са изискванията, причините да търся публичност на плановете за озеленяване, защо и как се предотвратява това. За щастие, Столична община разпозна надделяващия публичен интерес и предостави плановете. За съжаление, не мога да ги споделя директно заради това, което аз смятам за лобистки текстове в закона.

Мога обаче да опиша със снимки какво се вижда на място и какво е трябвало да бъде. Избрах тези четири обекта по няколко причини. Първо, защото инвеститорите се рекламират основно със заявки за окъпани в зелени сгради, коректност и лукс. Второ, защото всяка от тях показва различни аспекти от неспазването на изискванията и ефектът от тях. Трето защото те са в различни фази на строеж и експлоатация позволяваща ни да разискваме възможностите за реакция. Четвърто – просто защото минавам почти всеки ден покрай тях, което освен че ми позволява да следя развитието им, ме връща редовно към мисълта, че така повече не може да се продължава.

Това в никакъв случай не значи, че по някакъв начин инвеститорите, сградите или нарушенията, които може би са били допуснати, са специални или уникални по някакъв начин. Виждаме същите в цяла София и цяла България. Докато има премного строежи въобще без разрешение или надвишили етажите, усвоили покриви или дори имоти публична собственост, при озеленяването нещата са далеч по-разпознаваеми и лесни за доказване. Поне би трябвало са, ако се упражняваше контрол. Ако имате други такива примери, бих се радвал да ги споделите в коментарите с описание какво разпознавате, че липсва.

На снимката долу съм отбелязал първите два, на които се спрях – Диамант 2 и East Plasa Hotel. Тъй като предпочетох да съм изчерпателен, се налага да разделя примерите в два текста. Следващите два примера на сгради все още в строеж ще опиша утре. Снимките в галериите долу се сменят автоматично. Може да ги спрете с бутона за пауза горе вдясно.

Диамант 2

Сградата беше рекламирана като изключително зелена от инвеститора. Гледайки плановете за озеленяване, наистина изглежда така – 86 широколистни и 52 иглолистни дървета, 168 високи иглолистни храсти, над 6000 цветя и други храсти. Заявяват, че 41% от площта ще е в озеленяване, минимум 25% от която са високи дървета. Сградата се намира на поземлени имоти 68134.803.4008, 68134.803.4005 и 68134.803.4050 с обща площ малко над 7 декара. Те имат две отделни разрешителни за строеж с отделни изисквания за озеленяване. Това означава, че поне 2824 кв.м. от площта трябва да е в зеленина и трябва да има поне 59 високи дървета като минимум общо за двата строежа.

На място виждаме, че въпреки заявките на инвеститора, има 76 широколистни дървета, 7 иглолистни и не повече от 100 храсти от какъвто и да е вид. Отделно има 18 дървета, които не отговарят на изискванията, тъй като са долепени до бордюра с отстояние под два метра от улицата и под 70 см от тротоара (снимки 13 и 14 и всички отбелязани в жълто). Няколко други са твърде близо до фасадата или балкони, които отново ги дисквалифицира (снимка 16). Има още 23 дървета, които са всъщност в общински имот, който инвеститорът е на практика приобщил към комплекса (снимка 10). Там има и тяхна рекламна табела без разрешение за поставяне.

Споменатите над 40 дървета не може да се считат към озеленяването. От останалите обаче високите са не повече от 50, което е крайно недостатъчно, за да покрие изискванията. Друго любопитно нещо е, че половината са в първият етап на строежа, който е с отделно разрешение за строеж в парцел 4005. Там нещата изглеждат добре и отговарят на изискванията. Другият парцел 4008, който е значително по-голям и има отделно разрешение с отделно изчисление на озеленяването. Там липсват поне 55 дървета и коефициентът на високи дървета е значително под 25%.

Отделен проблем е самата зелена площ. На много места се вижда, че почвата е не повече от 5 до 10 см. дълбочина. Изискването по старата наредба е поне 30 см. и 60 см. където има дървета и храсти. Пример за това е инцидент от 2024 г., когато едно от и без това малките дървета беше премахнато и част от градинката пред него беше превърната в паркомясто. Под него личеше, че е оставено малко малко дълбочина, но и това беше бетонирано и бяха сложени плочи направо на бетона симулираща, че има почва отдолу (снимка 4). В последствие след множество сигнали и месеци напомняне на районния кмет все пак върнаха дървото и сложиха трева. Дървото обаче сега е в малка вкопана кашпа, а тревата е с не повече от 5 см. почва под нея. Т.е. дефиницията на бутафорно озеленяване.

Аналогична е ситуацията вляво, където предвидена за зелена площ има отново бетонна плоча точно над паркингите и същите плочи за паркинг. Пред същото място по план трябва да има пет дървета, но има само едно, което също няма достатъчно отстояние или почва, за да оцелее. На това и на други места части от задължителното озеленяване е изчезнало спрямо когато са получили акт 16. В някои случаи това се е случило след година. В други – в рамките на последващи разрешения за строеж с цел промяна на предназначение, където е имало промени в озеленяването на имота. Последното е дори документирано от районната община като част от сигнали.

На няколко стари сигнала за описаните случаи районната община на Изгрев отговаряше, че всичко е наред и отговаря на проекта и изискванията. Отказваха на няколко пъти да предоставят плана за озеленяване като част от този проект. Сега разбираме защо – липсват десетки дървета и не са изпълнили дори базисните изисквания за отстояния, дълбочина на почвен слой и висока дървесна растителност. В крайна сметка пет годишният срок по ЗУТ от оригиналното разрешение за строеж, в който имат задължение да правят проверки изтече в началото на 2026 г.

За щастие, има две последващи разрешения за строеж на това място за преустройство на помещения с изходи към улицата – медицински център и магазин. Извинението на районната община този път е, че срокът от първото разрешение за строеж е изтекъл, а новите разрешения не предвиждали промени по озеленяването. Това не значи, че такива промени не е имало и отговори на стари сигнали го доказва. Изискване в последвалите разрешения за строеж е да не се променя нищо по имота, включително параметрите на озеленяването. Към него задължително се прилагат оригиналните планове.

Особеното тук е, че чл. 63, ал. 5 от ЗУТ не разграничава разрешенията за строеж и срокът от пет години започва да тече отново. Конкретно районната община следва да установи към днешна дата дали озеленяването отговаря като дълбочина на почвения слой във всички лехи, като брой дървета и отстояние на оригиналния план и изискванията. При липса на документация какво са установили при проверки между 2021 и 2024 г. единствената хипотеза е, че промените са се случили във връзка и след промените на предназначението на двата обекта. Това се подкрепя от случая в края на 2024-та, където именно това беше установено, но не и възстановено според изискванията. Тогава изрично районният кмет описа, че е ограничил проверката си до тези няколко квадрата и е установил проблем свързан с преустройството на магазина. Длъжен е да го направи за целия имот и има срок от още поне три години.

East Plasa Hotel

За разлика от предишната сграда, тази влиза в експлоатация през ноември 2024-та и районната администрация има задължение до края на 2029 г. да следи дали всичко отговаря на изискванията. Разрешението за строеж обаче е от 2019 г., т.е. важи старата наредба за озеленяването.

Тук първоначално е важало изискването за 40% озеленяване и това е отчетено в първите скици, които видях. Там предвиждаха значително по-малка интензивност на строежа, дървета и градинки по високите етажи и прочие. Заради един отчетливо лобисти текст в чл. 27 на ЗУТ това се променя. Имотът изкуствено се разделя на две през 2020 от Здравков. По-малката част е от страната на бъдещият зелен ринг и се застроява почти напълно (с изключение на 4 дървета от снимка 9). Така основната сграда се води ъглова, отпадат всички ограничения и успяват да постигнат тази височина и степен на застрояване. На практика сградата е една и без каквато и да е възможност за разграничение.

Все пак, в проекта, разрешението на строеж и при влизане в експлоатация твърдят, че имат 33.28% озеленяване, 34.75% от които са висока дървесна растителност. Това е важно, защото това би трябвало да видим на място и както сами се досещате не е съвсем така.

При дърветата има проблем, но не толкова голям, колкото при Диамант 2. По план трябва да имат 56 дървета. Десет от тях следва да по терасите на 6-тия етаж. Трудно се виждат, а височината и структурата на терасите не позволява да са спазени изискванията за кашпите. Трудно е, но нека предположим, че там всичко в наред.

С тях дърветата на място стават 50. Голяма част от тях не отговарят на изискванията за отстояние едно от друго или размер на кашпа или клоц (снимки 13, 14, 15 и 23). Същото важи впрочем и за храстите в снимки 16, 17 и 18. В края на 2024 г. имаше още едно място с озеленяване отбелязано на снимка 19, което обаче после беше бетонирано. Дори с тези липси обаче покриват сериозно намалените изисквания при условие, че дърветата на 6-тия етаж съществуват и си затворим очите за отстоянията и почвения слой.

Тук фрапантното нарушение е друго. За да постигнат дори малкия дял от 33.28%, тази сграда залага много на вертикално озеленяване. Това значи увивни и други растения, които покриват няколко пероги, вертикално по огради и стени на сградата. Общо в плана има 7 такива места, които да допринасят цели 48% от общия коефициент на озеленяване.

На място не виждаме нито едно от тези вертикални озеленявания. На снимка 3 виждате озеленяване, което трябва да е значително по-високо по оградата, но представлява ниски храсти с почвен слой от около 20 см. На снимки 4 и 11 виждате нещо, което е трябвало да бъде перога покрита изцяло в зеленина допринасяйки над 350 кв.м. към общото озеленяване. Това включва както по самата конструкция, така и вертикално на оградата пред нея и пълзяща още 160 кв.м. по стените наоколо. На снимка 12 виждате, че над дърветата по план е трябвало да има още озеленяване, вероятно на мястото на терасите, както и пълзящо по стените. На снимка 24 виждате място, където е трябвало да има над 120 кв.м. вертикално озеленяване по същия начин върху перога, което липсва.

Така изпълненото озеленяване не надвишава 20% дори с много уговорки за недостатъчния почвен слой. В края 2024, но преди пускането в експлоатация имаше сигнал, че почти готовата сграда видимо не може да отговаря на изискванията на озеленяване, че кашпите са твърде малки и плитки, а дърветата и храстите няма как да оцелеят и да се развият. Тогава отговорът от районната администрация беше, че щели да видят като е готово. Месец по-късно са подписали протокол като част от приемателна комисия, че всичко е наред. Поисках този протокол като административен акт на публична институция, но районната община ми отговори, че го нямали, което не би следвало да е вярно. Поисках го от ДНСК, които също отказаха, защото засягало интересите на инвеститора, а той изрично отказал да бъде публикуван. Обжалвах това решение в съда и предстои заседание.

Под тази сграда ще минава скоро новият Зелен ринг. Липсата на озеленяване и способност да се задържа дъждовна вода означава, че рингът ще се превръща в река. Това вече се случва постоянно на улицата пред въпросния хотел. При последните дъждове беше толкова зле положението, че зеленикавата вода влезе право във фоайето на хотела (снимки 29 и 30). Въпросната отсечка от улица Тинтява, но само до входа на гаражите на въпросния хотел, както и паркът срещу хотела (снимки 27 и 28) бяха ремонтирани приоритетно с публични средства от районната община. На въпроси от жителите на района беше настоявано, че няма връзка. Същият хотел има проблем и с огромният видео билборд, който е незаконен по три различни начина (снимка 26). Сигналите към районният кмет отново остават без отговор.

Какво от това?

Това са само два примера, но типични за новото строителство в София и в цялата страна. Често изниква въпросът има ли възможност да се засичат тези проблеми още докато се строи сградата. Отговорът често е да. Доколкото озеленяването се „забожда“ и „постила“ малко преди пускане в експлоатация, много преди това се разпознават плитките кашпи, бетонните плочи на нивото на бъдещата зелена площ, липсата на резервоари за дъждовна вода или въобще място за дървета. Затова в следващата част ще споделя два примера на строящи се сгради с подобен преглед и сравнение с плана им.

Несъмнено задължение е на приемателната комисия да разпознае тези проблеми предвид, че има експерти в нея. От примерите виждаме, че това не се случва. Натрупването на такива случаи води пряко и непряко до доста от проблемите в градска среда, включително риск за безопасността и здравето на хората. Никой строеж сам по себе си не е виновен за това, но в съвкупност общото нехайство, неспазване на изискванията и дори грубо нарушаване на закона прикривани със съмнения за корупция допринасят до това, което наричаме презастрояване.

Разбира се, единствено циничността като типично българско качество ни води към предположението, че е намесена корупция. Не може да твърдим, че подобни практики е имало при който и да е от описаните тук примери. Ако прочитът ми на документите е неправилен, което би било също разумно предположение, то не може да говорим дори за административно нарушение, с което се изчерпва личното ми мнение относно разминаването между видяното на място и плановете, до които ми беше даден достъп.

Очаквайте утре следващата част от темата с още такива примери. В първата част от серията бях описал трудностите да стигна до тези документи.

The collective thoughts of the interwebz