Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/uEpFWeXkZ3s
Can This DIY Voice Assistant Hear Me Over Music?
Post Syndicated from BeardedTinker original https://www.youtube.com/shorts/XN-ojlqRDxQ
Саманта Швеблин: Да избягаме от езика, за да докоснем тялото на читателя
Post Syndicated from Стефан Иванов original https://www.toest.bg/samanta-schweblin-da-izbyagame-ot-ezika-za-da-dokosnem-tyaloto-na-chitatelya/
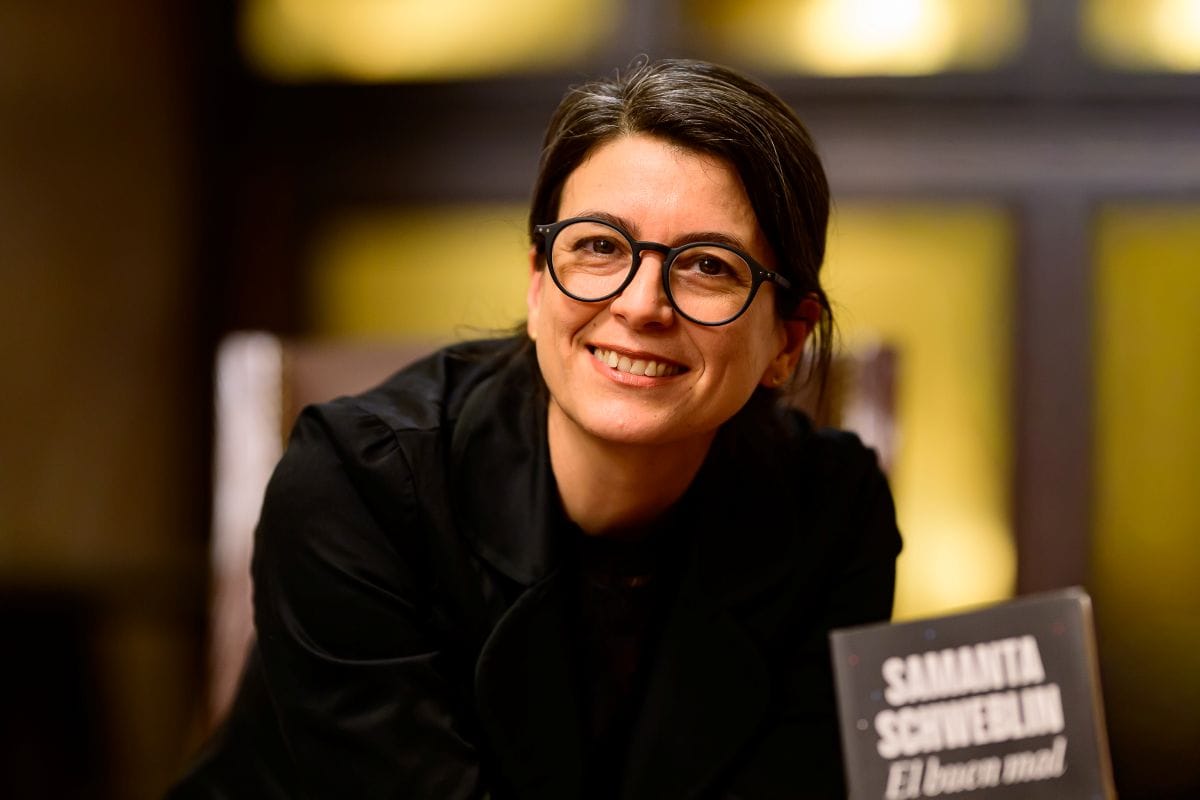
Саманта Швеблин е аржентинска писателка от Буенос Айрес, която от 2012 г. живее в Берлин. Смятана е за един от най-силните гласове в съвременния испаноезичен разказ, а книгите ѝ са преведени на повече от двайсет езика. Носителка е на Националната литературна награда на САЩ за преводна литература и на наградата „Шърли Джаксън“; три пъти е номинирана за Международния „Букър“. През април 2026 г. последната ѝ книга „Доброто зло“ – пет разказа за сложните връзки между родители и деца, спечели новоучредената награда „Аена“ за испаноамериканска проза в размер на един милион евро. Швеблин гостува в България по покана на Културния център на Софийския университет, за да представи именно „Доброто зло“ в превод на Калоян Игнатовски (изд. „Лабиринт“). Срещата с нея беше на 30 октомври от 17:00 ч. в аулата на Софийския университет.
Разказите Ви често започват с обикновена домашна сцена, която почти незабележимо се накланя към ужаса. Откъде започва историята за Вас – от образ, страх или изречение?
Ако трябва да избера от трите, бих казала страха, защото той идва пръв. После нещо привлича погледа ти или чуваш изречение, което те сепва, но то е интересно само защото страхът вече е бил там. Всичко започва със силна и много конкретна емоция, а колкото по-конкретна е, толкова повече време отнема да я обясниш. Американската есеистка Ребека Солнит има едно изречение, което непрекъснато повтарям, и то е, че
добрата книга е сърце, което бие в чужди гърди.
Когато пишеш, имаш страха, той те свързва с образи, образите ти дават думи. После идва читателят, взема думите, изгражда образа и получава страха. И този страх трябва да е съвсем точен. Писането е мост между твоите гърди и гърдите на някой друг.
Много от текстовете Ви сякаш измерват разстояния – между родител и дете, между изречение и страх, между непознати, между видяното и почувстваното. Колко близо допускате читателя, преди да задействате капана на страха?
Възможно най-близо. Може би в началото не толкова, защото обичам историите да изглеждат кротки, прости, реалистични. Но щом приближиш нещо съвсем до себе си, виждаш колко е странно. Може би затова обичам разказа, движението в него е бързо. Не ти трябват двеста страници, за да доближиш до очите си нещо, което е изглеждало далечно. Като зуум е. Буквално. Не бях се замисляла досега.
Критиците често описват прозата Ви с думи като „хорър“ или „нечовешко“. Осветляват ли тези етикети това, което правите, или го опитомяват?
Опитомяват го, но разбирам какво имате предвид. Книгата в крайна сметка е предмет, който трябва да бъде сложен на определен рафт, защото живеем в капитализъм. Но литературата, която най-много обичам да чета, е тази, за която самата аз не знам на кой рафт да я сложа – там, където жанровете се смесват и идеите си противоречат. Литературата е обратното на радикализацията, в която живеем. Тя винаги показва как едно нещо може да бъде едновременно добро и лошо, като в заглавието на книгата. Хорърът е по-скоро това, което се случва в главата на читателя. Ако подчертаете думите на ужаса в книгата ми, няма да намерите призраци, Дракула, кръв, никой никого не убива. Когато пишем, слагаме думи на страницата, но пишем и в съзнанието на читателя и не го казвам метафорично. Има думи, които можеш да докоснеш в книгата, и думи, които се случват само в главата на читателя. Мисли като „винаги е била тя“ или „той ще я убие“. Или по-лошо – „това може да се случи на мен и ако се случи, не знам дали ще оцелея“. Това е ужасът, и то най-лошият, защото не се случва на персонажа. Случва се на теб.
Това е буквално реалното.
Точно така.
Кои автори, които не се побират на никой рафт, обичате и Ви вдъхновяват?
Първо се сещам за Шърли Джаксън. Някои романи могат да се нарекат хорър, но разказите ѝ не са хорър, макар да са ужасяващи и великолепни. Изключително важен за мен, когато като дете четях първите си книги за възрастни, беше Рей Бредбъри – уж кротка научна фантастика, а всъщност страшна, много страшна. И в същото време невероятно позитивна. Оттогава не съм чела друг автор, който да пише за толкова мрачни неща и да е такъв оптимист за бъдещето. После открих Балард. Спомням си и разказите на Кафка – толкова мрачни. Никой не говори за това, но Кафка е много смешен.
Кундера винаги го е казвал…
Може би защото забравяме, че четенето е наполовина писател и наполовина читател. Когато слагаме книгите по рафтовете, слагаме там само половината. Читателя го няма, трябва да отвориш книгата и да четеш, за да се случи. Затова една книга може толкова да се промени с времето. Читателите се променят.
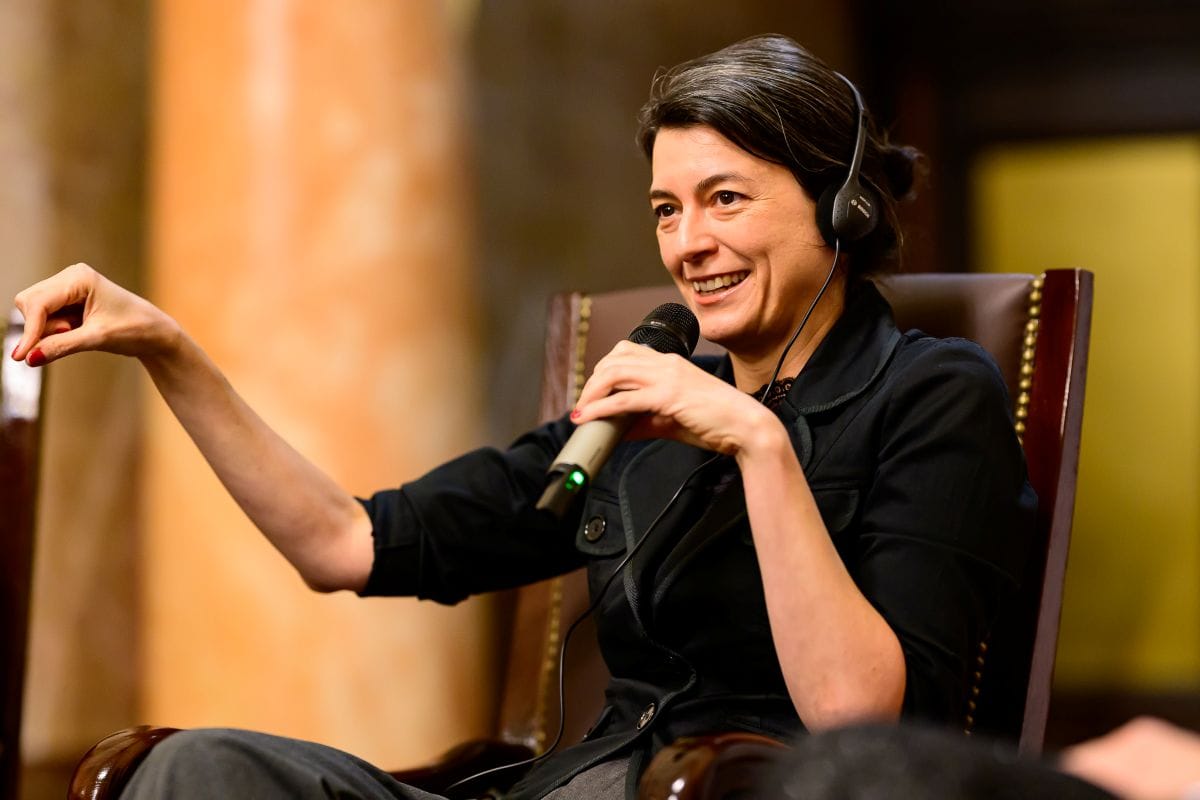
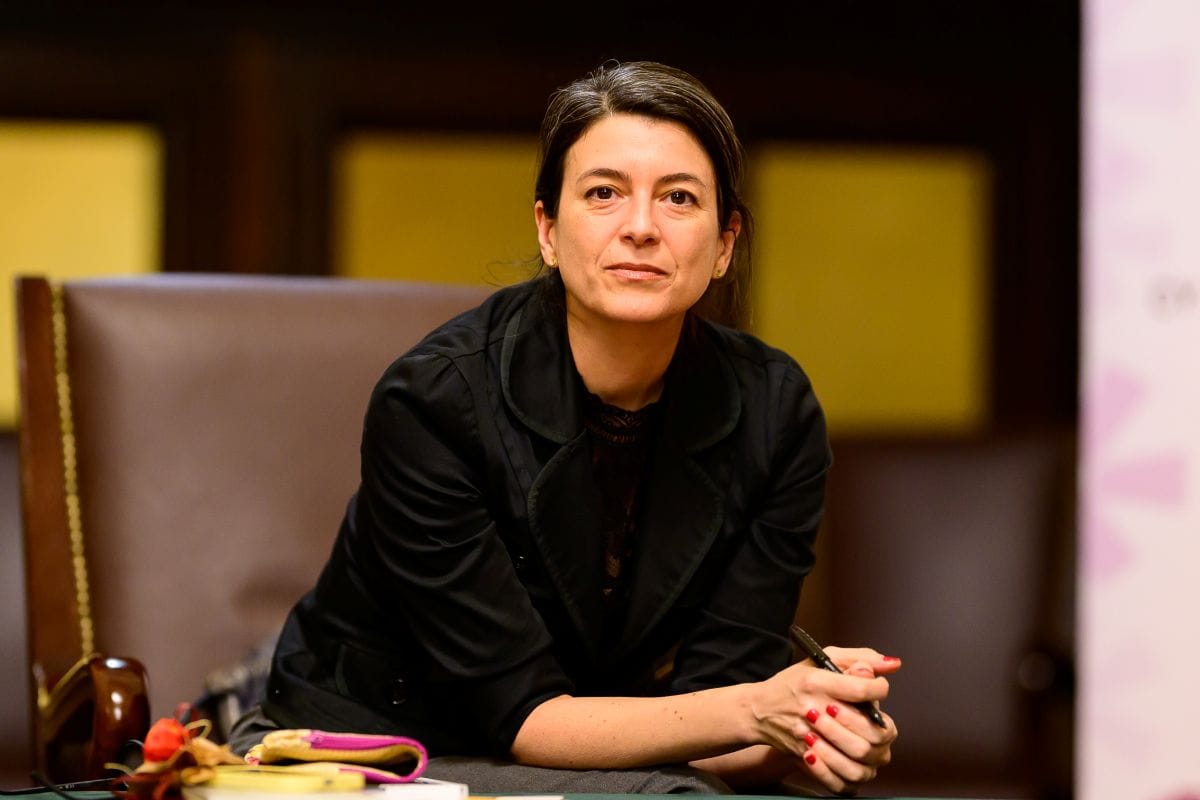
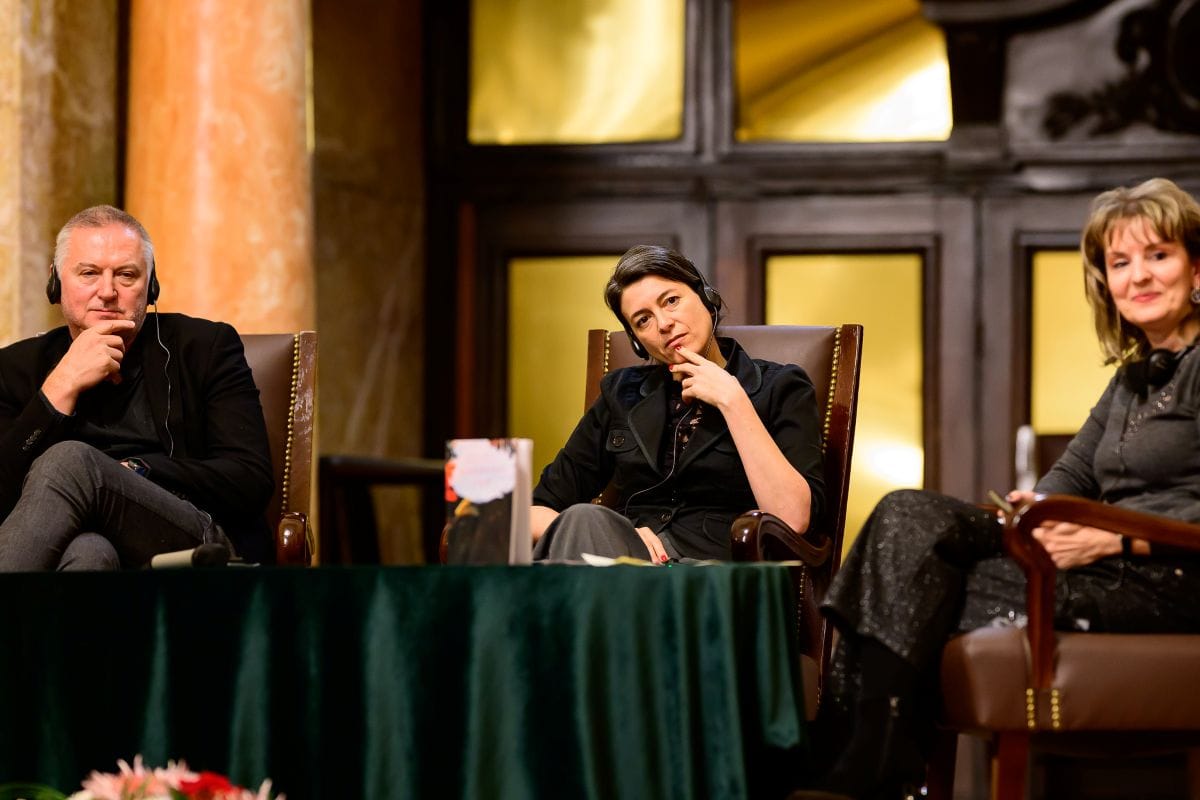
Саманта Швеблин в София © Снимки: Илиян Ружин
Прозата Ви сякаш усеща тревогите на времето, преди да станат заглавия във вестниците за отровени пейзажи, наблюдение или близост, опосредствана от машини. Пишете ли с поглед към определен социален проблем, или той се промъква в историята, която е била за нещо друго?
Истинският отговор е, че не знам. Никога не взeмам съзнателно решение – „това ще е проблем в бъдеще, трябва да пиша за него“. Нещата не се случват от днес за утре. Има шум и по-късно разбираш, че е бил звукът на нещо, което идва. Когато писах „Хиляди очи“, нямаше начин човек като мен да реши да пише за технологии, няма нищо по-скучно за мен. Но ме вълнуваше това, че живеем затрупани от технологии, без да мислим за тях. Едно и също се повтаряше отново и отново. Чета например стихотворение в списание, в което героят два-три пъти праща съобщения по WhatsApp, и някой го нарича „технопоезия“. Или роман, в който присъстват социални мрежи, и изведнъж той е научна фантастика. Това е шумът. Натурализираме технологиите в живота, но щом се появят в книга, решаваме, че не принадлежат на реалността. А литературата е пространството, в което мислим следващите си стъпки и в което се изпитваме и подготвяме за бъдещето. Започнах да си играя с този проблем и така се появи „Хиляди очи“. Темите не са планирани, но усещаш, че вече са в живота ти и са неудобни. И искаш да мислиш за тях.
Днес говорим с чатботове и се доверяваме на алгоритми. Започнала ли е реалността да пише историите, които някога сте си представяли?
В „Хиляди очи“ има устройство, но големият въпрос на романа е как общуваме с другите чрез него. Фокусът ми остава върху хората. С чатботовете говорим с нещо друго. Много е важно да престанем да наричаме тези неща изкуствен интелект, защото те в никакъв случай не са такъв. Хитро е, че ни научиха да ги наричаме така. Това са езикови системи за вероятности и предположения. Пълната противоположност на онова, което хората са правили през цялата история, когато са изобретявали или откривали нещо ново. Ако кажеш „куче“, езикът, основан на предсказване, ще каже „кафяво“, защото това е най-често свързаната дума. А прочутият разказ на Габриел Гарсия Маркес се казва „Очи на синьо куче“. Ето това правим ние. Всеки път, когато намерим нещо извън системата, предприемаме първата крачка към истинско откритие. Когато продължаваме да говорим с тези машини за предположения, се придвижваме към най-очевидния си начин на съществуване. Ставаме глупави, скучни и предвидими, а в това има само нещастие. Убедена съм. Не бих казала дори, че е опасно. Скучно и тъжно е. Като да затваряш една след друга всички врати навън. Точно обратното движение на онова, което прави литературата.
Слушайки Ви, си спомних, че в „Махалото на Фуко“ Умберто Еко измисля компютър на име Абулафия, който комбинира текстове и пише литература. Но там това е шега.
Трябва да препрочетем тази книга.
Какво може да направи писателят днес, във време на разкъсано внимание, моментално възмущение и лесен гняв? Разказът – със своята сгъстеност и отказа му да обяснява – форма на съпротива ли е?
Разказът изисква много от читателя. Добрият роман също, но дори да си страхотен читател, ще ставаш много пъти, ще продължаваш живота си и ще се връщаш. Разказът иска да си напълно съсредоточен двайсет-трийсет-четирийсет минути. Това вече не е лесно, губим вниманието си. Но има нещо особено в несигурността. Обичам това състояние и мисля, че е сърцевината на всяка история. Историята започва, когато изведнъж настъпи несигурност. Имаш персонаж, звънецът звъни и се чудиш кой е. И историята потегля. В живота бягаме от несигурността, не я обичаме. Но във фикцията, когато наистина внимаваш, тя е съвсем отворено пространство. Умира бащата на персонажа, твоят е жив и затова не си толкова разтревожен. Но си задаваш много интересни въпроси. Каква е връзката ми с баща ми? Ами ако го загубя сега? Казах ли му всичко, което исках? Вниманието е напрежение. Когато в книгата има напрежение, ти се отваряш. Споменахте отказа да се обяснява; когато историята стане абстрактна, следиш по-малко сюжета и повече това, което става в главата ти. Затова е толкова силна. Това е танц с писателя. В абстракцията той ти дава време да си играеш с мислите си, без да изпускаш сюжета. Двете трябва да се случват едновременно. Толкова е сложно, а се случва. Като магия е.
Симон Вейл, философката и писателката, казва, че вниманието е най-висшата форма на молитва.
Обичам тази нейна мисъл. Тя казва още, че когато наистина внимаваме, нещо зло в нас умира. Защото, когато внимаваш истински, се свързваш със себе си и с това, което е важно за теб, свързваш се и със света. Злото започва след прекъсването на тази връзка.
Децата във Вашата проза са уязвими, но и странни, непрозрачни, понякога плашещи. Какви възрастни си представяте, че ще станат днешните деца?
Много страшен въпрос. Говорихме за вниманието и тези деца вероятно ще трябва много да се борят за своето. Как ще знаят какво искат, кое е важно? Мрачно е да се мисли за това. Но преди няколко седмици сръбският ми преводач ми каза нещо, за което още мисля. Говореше за протестите в Сърбия. „Тези деца, които току-що промениха света в моята страна – каза ми той, – са децата, на които съм преподавал, без да им вярвам. Мислех, че не внимават, че не мислят за това, за което трябва, че не учат, че не се интересуват от политика. Това беше огромен урок за мен.“ Малко ужасяващо е, защото ние, възрастните, сигурна съм, че мнозина ще се съгласят, виждаме как и колко губим от способностите си. Не мога да се съсредоточавам както преди. Помня как четях Гарсия Маркес по два часа без прекъсване, пълна с радост. Днес половин час четене би бил пълен успех, защото тялото ми вече посяга към телефона. Тази битка сме я загубили. И се плашим, мислим, че може би и младите ще се изгубят. Не знаем.
Пак несигурност.
Пак несигурност.
Страхът често е Вашата суровина. Може ли страхът да бъде форма на внимание? Дори на грижа?
Абсолютно. Затова казвам, че напрежението е внимание. Щом включиш в текста опасност, която наистина може да докосне реалността на читателя, той внимава. Но е малко по-сложно, защото страхът включва и предразсъдъците ни и това е нормално – така работят телата и умовете ни. Ако четеш реалистична проза и някой влезе в стаята с пистолет, предразсъдъците ти казват, че това е лош човек, ще умрем, може да избягаме по стълбите или да се скрием. Помагат ни да реагираме. Във фантастиката и фентъзито също има много правила как да се защитим. Ако се появи Дракула, знаеш, че трябва да дръпнеш завесите, за да влезе светлина, и може би да имаш чесън в джоба. Но в несигурността няма правила. Това ѝ е хубавото. Когато се случи нещо извън правилата и очакванията, предразсъдъците не помагат. Не знаеш какво да правиш, трябва ти информация. И тогава наистина внимаваш.
Как научихте – чрез писане, опит, четене или четене на глас на собствените си разкази – какво да оставите встрани, за да има сгъстено напрежение?
Мисля, че си играя със себе си като читател. Научих се да пиша, разбира се, пишейки. Но още повече се научих, четейки книги с изключително внимание, и то не само към книгата, но и към собственото си тяло и ум. Питам се непрекъснато какво става с мен като тяло, като мозък, като сърце, като стомах. Може би така не се чете най-добре, защото разсейва. Но откритията са невероятни. Откриваш, че един ред не намясто те изважда от книгата. Когато се разсея, спирам и започвам да чета назад, за да разбера къде съм се отклонила. И винаги има такова място. Винаги е конкретна фраза, понякога само две думи. Тогава се опитвам да разбера защо точно те. Когато изучаваме литература и творческо писане, се фокусираме много върху писателя – защо е взел това решение или какво иска да каже. Но трябва да внимаваме и с читателя. Читателят знае много, защото работи с истинския универсален материал на фикцията – тялото. То е нещо изключително органично и мъдро, по-мъдро от нас. Всеки читател е натоварен със собствения си език, култура и живот, но тялото е едно и също в Китай, в Куба и в Германия. Може да звучи странно да се говори за тяло, когато говорим за литература, защото литературата е изградена от език, а езикът е нещо, което сме измислили. Но най-добрата литература се случва, когато фикцията успее да се изплъзне от езика и да докосне тялото. Градим литературата с език, но трябва да избягаме от него, за да докоснем наистина тялото на читателя.
Попитах Ви, защото, когато Ви чета, имам усещането, че пишете като поет, но и като хирург. Много прецизно. Представете си света след тринайсет години, през 2039-та. За какво се страхувате, че ще е изчезнало? Какво се надявате да е оцеляло? И каква история бихте искали да пишете тогава?
Надявам се книгите още да са тук и мисля, че ще бъдат. Не съм песимистка в това отношение, защото книгата е много странно нещо. Технологията промени всички изкуства – киното, театъра, музиката. Книгата не се промени. Може би носителят се е сменил – може да четеш на електронен четец. Но единствената технология, от която книгата има нужда, е нашият мозък. Затова книгата определено ще остане. Надявам се да не сме изгубили вниманието си и да не сме спрели да мислим заедно с другите хора вместо с машините. За първи път в историята започваме да мислим само със себе си, защото, когато говорим с машини, говорим със собствените си най-обикновени и очевидни мисли. А вратите и прозорците се отварят, когато сме достатъчно смели да мислим с някой, който мисли различно от нас и знае други неща. Ако изгубим това, свършено е с нас. Какво бих искала да пиша? Добра книга, която ни позволява да продължим да правим това. Надявам се да пиша и след трийсет години.
Какво Ви дава утеха и оптимизъм?
Знам, че е странно, но утеха ми дават онези много редки моменти във фикцията, когато наистина внимавам. Тогава имам чувството, че мозъкът ми е спокоен. Вече не е изгубен, съсредоточен е, а когато съм съсредоточена, съм по-спокойна. Склонни сме да мислим, че вниманието е нещо стресиращо, което изисква огромно усилие. Така е, когато не си трениран. Когато си добре трениран, вниманието ти помага да си почиваш. Това е утеха за мен.
Значи обичате медитацията?
Да, абсолютно.
AWS Weekly Roundup: GPT-6.1 Terra on Bedrock, Step Functions as agent tools, and more (November 2, 2026)
Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-gpt-6-1-terra-on-bedrock-step-functions-as-agent-tools-and-more-november-2-2026/
The agentic launches that stayed with me last week had nothing to do with how capable a model is. They were about reach. AWS Step Functions, which already orchestrates over 220 AWS services, can now be handed to an agent as a tool, so workflows teams already trust became callable without a rewrite. In the same week, the AI blog published how one engagement platform exposed roughly 400 internal API operations the same way. Neither story involves rebuilding anything, only describing what exists and letting the agent find it.
The other thread was cost. OpenAI’s newest Terra model reached Amazon Bedrock priced well below the model beside it, and two post-quantum launches landed for a deadline nobody can put on a calendar yet. Now, let’s get into this week’s AWS news…
Headlines
OpenAI GPT-6.1 Terra is now generally available on Amazon Bedrock, and what interests me is where it sits rather than what it tops. Terra is the everyday-workload line of the GPT-6 family. In OpenAI’s Agents’ Last Exam evaluation it scored 15 percentage points higher than GPT-5.6 Terra, performed on par with GPT-6 Astra, and completed tasks more than three times faster than both. Those are OpenAI’s figures, not an independent test. The price is what I would check first: input and output tokens are at least 50% lower than GPT-6.1 Sol and GPT-5.6 Terra. It takes up to 1 million input tokens with text and image input, and you can reach it from the Bedrock APIs or ChatGPT Work and Codex.
AWS Step Functions workflows are now available as AI agent tools through Amazon Bedrock AgentCore Gateway, which connects agents to tools over the Model Context Protocol (MCP). The division of labor is the idea: the agent decides when to run a workflow and what input to pass; Step Functions runs each step exactly as you defined it. A support agent can trigger a refund, and the eligibility check, the manager approval, and the credit still happen in that order every time, because the ordering was never the model’s to improvise. Your existing Standard and Express workflows qualify as connector targets, and agents can also look up runs. It’s available in all Regions where AgentCore Gateway is, at standard rates.
Last week’s launches
Here are some launches and updates from this past week that caught my attention:
AWS Key Management Service now supports ML-KEM for post-quantum key encapsulation – You can now establish a shared secret with a post-quantum algorithm using AWS KMS keys, with private keys in FIPS 140-3 Level 3 validated HSMs. All three NIST FIPS 203 parameter sets are supported through Encapsulate, which produces a random 32-byte shared secret and its ciphertext, and Decapsulate, which recovers it. The threat is harvest now, decrypt later: an adversary records today’s key exchange and recovers the secret once quantum computers are powerful enough. It’s available everywhere KMS runs except the Middle East (UAE and Bahrain) and China Regions. Amazon Aurora PostgreSQL added post-quantum TLS key exchange the same week, on versions 18 and higher.
AWS IAM Identity Center now supports cross-Region trusted identity propagation – You can now carry a user’s identity with their request to AWS services in another Region. This removes a genuine architectural constraint: trusted identity propagation used to require every service accessing that identity to sit in the same Region, which left two unappealing options, broad IAM roles that cannot distinguish individual users, or consolidating all your services into a single Region. Now the identity travels with the request automatically, so you grant access by user and group membership and audit who accessed what. It’s available at no additional cost everywhere IAM Identity Center runs.
Amazon ECS now supports GPU sharing with NVIDIA Multi-Process Service (MPS) – You can now run multiple Amazon ECS tasks concurrently on a single NVIDIA GPU, the practical answer to work that only ever uses a fraction of one, like small-model inference and multi-model serving. You declare the GPU memory each container needs and can optionally cap its share of GPU compute, and ECS places tasks on GPUs with available capacity as your services scale, with no code changes. It works on ECS Managed Instances and ECS on Amazon EC2, and on Managed Instances it watches the MPS control daemon and replaces the instance if it turns unhealthy. It’s available in all commercial and AWS GovCloud (US) Regions.
AWS Lambda supports Seekable OCI (SOCI) lazy loading for Lambda Managed Instances – You can now have AWS Lambda fetch only the files needed at each stage of startup instead of pulling a whole container image first, which AWS puts at up to 70% off container startup time. You create a SOCI index, push it to Amazon ECR, point the image URI at the indexed tag, and Lambda detects it automatically. The technique also reached Amazon SageMaker AI training and processing jobs, with benchmarks: lazy loading held at 3 to 11 seconds regardless of image size, against a median 3 minutes 42 seconds for a 13.2 GB image, a range they report as 8x to 46x.
Amazon EKS Auto Mode now supports Kubernetes Gateway API – You can now declare how traffic reaches your applications with Gateway and HTTPRoute resources on Amazon EKS without installing a separate controller, and EKS Auto Mode provisions and manages the underlying AWS load balancing infrastructure. You get HTTP and gRPC routing, cross-namespace routing, weighted traffic splitting, header-based routing, and automatic TLS certificate discovery through AWS Certificate Manager. Existing Ingress workloads keep working alongside them, so this is additive rather than a migration. Gateway API support is included with EKS Auto Mode; standard load balancing charges apply.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news
Here are some additional posts and resources that you might find interesting:
How Nubank automated disaster recovery with the AWS DevOps Agent – Nubank serves more than 140 million customers across Brazil, Mexico, and Colombia, and classifies over 300 business flows as critical, each tested on a regulator’s schedule. Nubank reports that handing evidence collection and report writing to the AWS DevOps Agent cut a test cycle from about 4.3 hours to roughly 40 minutes, and quadrupled flow coverage in 2026 to more than 160. One execution terminated more than 900 EKS instances under synthetic traffic with AWS Fault Injection Service, producing the evidence its regulator needed.
How MoEngage turned over 400 APIs into agent tools with AgentCore Gateway – Roughly 400 internal REST API operations, built by 25 teams, sitting in private VPCs across seven Regions, with tenant identity that could never become a parameter the model gets to set. MoEngage estimates the managed path saved about six months of platform engineering. The detail worth stealing: a full tool listing would have crossed 20,000 tokens per connection, so agents search for tools by describing a task instead of receiving the catalog.
Reducing petabyte-scale S3 storage costs with evidence-based lifecycle rules – The hard part isn’t deciding to act, it’s knowing which data has gone cold and where it can safely live. This uses S3 Storage Lens groups and Storage Class Analysis to prove access patterns before moving anything. In the engagement described, 5.8 PB of logs in Amazon S3 Standard at approximately $241,000 per month showed an access ratio below 0.1% past 90 days, and a 90-day transition to Glacier Instant Retrieval cut the bill by roughly 70%, a figure the author ties to that workload.
Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:
AWS re:Invent – re:Invent returns to Las Vegas from November 30 to December 4, with more than 2,200 sessions. The event catalog is live and reserved seating is open, so register and claim your spots before they fill up.
AWS Community Days – Community-led conferences planned and delivered by community leaders. The 2026 season is winding down as re:Invent approaches, so check the hub for what’s still on.
Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.
That’s all for this week. Check back next Monday for another Weekly Roundup!
– Daniel Abib
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
По буквите: Линч, Рой
Post Syndicated from Зорница Христова original https://www.toest.bg/po-bukvite-linch-roi/
„Отвъд морето“ от Пол Линч
превод от английски Иглика Василева, София: „Лист“, 2026
Двама души в рибарска лодка. Не е ясно докога, може би завинаги. Звучи като притча, като „Животът на Пи“, но с хора (всъщност в края на „Животът на Пи“ Ян Мартел подсказва, че също говори за хора…). Звучи като кръстоска между морско приключение и филм на ужасите – защото повечето съвременни сюжети, в които човек е принуден да търпи неопределено време компанията на друг човек – приятел, любима, роднина, – ни водят именно в този жанр. Човекът отдавна не мечтае за себе си в духа на „робинзониадите“ – как ще сътвори цивилизацията наново с голи ръце и с малко помощ от ближния.
Още повече че авторът е Пол Линч – създателят на смразяващата „Пророческа песен“, в която една днешна жена и майка не успява да повярва навреме, че страната ѝ бързотечно се е превърнала в опасна диктатура – и плаща непосилна цена за своята цивилизационна инерция, за желанието да продължи още малко постарому.
„Отвъд морето“ започва без заобикалките на „нормалността“. Още в началото виждаме „стария моряк“ Боливар, усещаме какво ще се случи, когато влезе в морето късно, въпреки предупреждението за буря, защото разни съмнителни хора го търсят. Дори младият му спътник Хектор предусеща нещастието и все пак ето ги – откъснати от света, живи след бурята, но с неработещ мотор, насред нищото,
насред времето – нашето време с плаващите в океана острови от боклуци, но и насред вечното време на всички истории за захвърлени сред вълните човеци.
Двамата герои са противоположности, но не дотолкова, че да представляват някакви архетипи – единият е стар, облъскан от живота, другият е млад, леко смотан… Различават се помежду си дотолкова, доколкото всяко човешко същество се различава от съседното. Друг човек.
Редуват се моменти на сътрудничество и конфликти на фона на съпътстващия ги лош късмет в набавянето на храна и вода и кратките изблици на надежда. Опитният „стар моряк“ се ядосва на липсата на инстинкт за самосъхранение у младия; „младият“ – на готовността на стария да жертва всичко в името на въпросното оцеляване, включително кратките, но опасни възможности за радост, като да поплуваш малко в океана. И разбира се, готовността му да бъде жесток към другите, в случая – към уловените птици. Препратката към Колридж и неговия албатрос е съвсем явна и отчетлива.
Това, което прави романа потресаващ обаче, не е постапокалиптичното съжителство между двамата, а онова, което се случва на финала, след като сюжетът завива в ненадейна посока, но старият моряк не разбира – отказва да разбере и да приеме какво се е случило. И точно този смразяващ финал носи и надеждата на книгата – показва каква физическа, неудържима нужда имаме един от друг.
„Моят подслон и моята буря“ от Арундати Рой
превод от английски Юлия Гешакова, София: изд. „Лабиринт“, 2026
В известен смисъл това също е книга за съжителството и сложните отношения между двама души, този път майка и дъщеря. Те не са сами насред океана, напротив, общуват през море от хора, понякога не се виждат с години по свое желание и все пак остават „в една лодка“ от началото до края. Дори когато се оттласкват една от друга.
Книгата проследява пътя на самата писателка – от детските ѝ години до днес. В романа има куп други неща отвъд отношенията с майката: проблемите на идентичността, любовта, реалностите на това да си жена в Индия, социалната ангажираност, политическите борби… Но отношенията с Мери Рой – амалгама от обич, възхита и негодувание, нужда от оттласкване и потребност от валидация, гняв и жалост – са като че ли основата, на която се развива всичко останало.
Мери Рой е достатъчно ярък персонаж сама по себе си – основателка на легендарно училище в Керала, истинска героиня за местните жени, успяла да промени закона, така че дъщерите да не бъдат оставени без наследство… феминистка, която успява да даде ясен урок на момчетата, опитващи се да тормозят съученичките си. И властна, безмилостна, нетърпима жена, която крещи по помощниците и най-вече по собствените си деца, която е способна многократно да те изкара от колата и да те остави сам на магистралата, независимо на колко си години, да те нарече какъв ли не публично, да те замеря с разни неща…
Отношенията на Мери и Арундати са магнетични за читателя не само защото осигуряват нужните за сюжета спойка и напрежение, а и защото човек неизбежно открива нещо от себе си там – било в едната роля, било в другата, не непременно в отношенията родител–дете. Независимо дали сте били някога в Индия, дали знаете какво точно е направила Индира Ганди по време на Извънредното положение, какво прави днес Моди, как изглежда национализмът в тази страна, в какъв свят са принудени да живеят жителите на изумително красивия Кашмир, какво е да си в Индия и да си мюсюлманин, да си жена или пък независим творец и т.н. Може да не знаете или да не ви интересува колко села са залети при строежа на язовира, срещу който протестира носителката на наградата „Букър“, може да не сте много наясно защо е готова да живее в гората с партизани, чиито методи не споделя напълно, но
основата на книгата – трудни отношения с близък човек – е универсална.
Възрастният, който иска да защити детето, което е бил. Смесицата от обич и страх. Болката при разрив с близък човек. Напрегнатата драма на семейния скандал. Но и облекчението, когато усетиш близост и обич, и симпатия след разрива, когато се научиш от уж прокудения вуйчо да обикнеш провала си, когато впиянченият баща е смешно, безобидно и някак симпатично присъствие, когато майката, от която си бягал, се окаже твоя вярна подкрепа точно когато трябва.
Универсалността на този разказ те засмуква и изведнъж ти се иска да узнаеш и онова, което уж е било удобно далече извън полезрението ти. И в това според мен е истинската сила на книгата – че те поставя в центъра на каузите си, че те пробужда за твоите собствени. Семейната драма става социална драма, а ти си част от нея.
В емблематичната си колонка „Ходене по буквите“, започната още през 2008 г. във в-к „Култура“, Марин Бодаков ни представяше нови литературни заглавия и питаше с какво точно тези книги ни променят. В началото на 2020 г. той я пренесе в „Тоест“. Вярваме, че е важно тази рубрика да продължи. От човек до човек, с нова книга в ръка. От края на 2021 г. по буквите тръгна Зорница Христова.
Активните дарители на „Тоест“ получават 20% отстъпка от коричната цена на всички книги на над 15 български издателства. Кои са те – вижте в условията на Читателски клуб „Тоест“.
Midterm Elections #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/iJIPA0cYK_8
Shutting the Door on the XCPE Botnet (Threat Intelligence)
Post Syndicated from corbet original https://lwn.net/Articles/1104847/
The Google Threat Intelligence blog describes,
in great detail, the XCPE botnet, which has just been taken down.
Last week, Google and industry partners dismantled the XCPE
backdoor which enrolled more than 1.3 million set-top boxes into a
botnet. We assess with high confidence that the backdoor and botnet
were intentionally developed, deployed, and operated for financial
gain by Videostrong Technology Co., an Android Original Equipment
Manufacturer (OEM) and Original Device Manufacturer (ODM).Videostrong monetized the backdoor by selling access to criminal
affiliates and loading those affiliates’ malware modules onto
infected devices. These secondary modules were conducting ad-fraud;
silently enrolling infected devices into residential proxy
networks; and loading additional malware onto XCPE-compromised
devices.
[$] Managing the kernel CVE flood
Post Syndicated from corbet original https://lwn.net/Articles/1100894/
We recently looked at how the
kernel community is dealing with the firehose of vulnerability reports, but
said little about how users of the kernel are responding. At the 2026 Linux Plumbers Conference, Amazon employees
Dylan Johnson and Justinien Bouron discussed the problem from the point of
view of engineers trying to keep AWS running and secure in the face of a
storm of CVE disclosures. The kernel community’s longstanding advice is to
run current kernels, and that turns out to work — sort of.
Tor Browser 16.0 released
Post Syndicated from jzb original https://lwn.net/Articles/1104846/
Version
16.0 of the Tor Browser
has been released. This is the first stable version based on Firefox ESR
153. Notable changes in this release include support for Linux on 64-bit Arm,
redesigned settings, and a “generic window titles” feature to help prevent other
applications from snooping on one’s browser activity. Tor Browser for
Android has had a number of interface updates to Google’s Material
Design 3 design language.
This release also follows Firefox in ending support for 32-bit x86 Linux
systems. See the full
changelog for all of the updates and bug fixes.
Security updates for Monday
Post Syndicated from jzb original https://lwn.net/Articles/1104844/
Security updates have been issued by AlmaLinux (firefox, java-17-openjdk, kernel, kernel-rt, mariadb:10.5, podman, python-jwt, python27:2.7, python38:3.8 and python38-devel:3.8, python39:3.9 and python39-devel:3.9, ruby:2.5, ruby:2.7, thunderbird, util-linux, and virt:rhel and virt-devel:rhel), Debian (chromium, eog, imagemagick, python-aiohttp, thunderbird, and vim), Fedora (asciinema, atuin, btrfs-backup-ng, clevis, gcc, janus, kernel, libheif, libreswan, mingw-expat, mupdf, nautilus, nicotine+, ntpd-rs, openscap, perl-DBI, python-streamlink, python3.12, retsnoop, ruby, rust-cargo-deny, rust-cargo-rpmstatus, rust-ctutils, rust-gst-plugin-reqwest, rust-rbspy, rust-resctl-bench, rust-rpki, rust-rustls-webpki, rust-sequoia-chameleon-gnupg, rust-sequoia-git, rust-sequoia-octopus-librnp, rust-webpki-root-certs, rust-webpki-roots, tpm2-tss, and vhs), Oracle (.NET 8.0, .NET 9.0, aspell, bind9.18, curl, httpd:2.4, java-1.8.0-openjdk, kernel, libXi, mod_auth_openidc:2.3, nodejs:24, python-pillow, and tomcat), Red Hat (libxml2), Slackware (libarchive), and SUSE (buildah, curl, docker, gnutls, nodejs22, and suseconnect-ng).
Qualcomm Validates HBC Stacked Memory Ahead of 2027 Dragonfly AI250 Sampling
Post Syndicated from Ryan Smith original https://www.servethehome.com/qualcomm-validates-hbc-stacked-memory-ahead-of-2027-dragonfly-ai250-sampling/
Qualcomm today is announcing that they have completed initial validation on their High Bandwidth Compute technology. The DRAM-stacked-upon-compute architecture moves on to commercialization, with Dragonfly AI250 set to sample in the first half of 2027
The post Qualcomm Validates HBC Stacked Memory Ahead of 2027 Dragonfly AI250 Sampling appeared first on ServeTheHome.
How we halved DNS build delay and cut memory use by 85%
Post Syndicated from Alex Fattouche original https://blog.cloudflare.com/dns-targeted-zone-builds/
When I last wrote about our DNS propagation pipeline in 2022, the Zone Builder received about 250 DNS record changes per second. Today it receives about 700, nearly three times as many, plus about 100 other events, such as zone setting changes. However, the number of events was never the real problem. The problem was the kind of work some of those events needed, and how that work grows with the size of a zone. Some zones now hold more than 20 million records, and we expect them to keep growing toward hundreds of millions.
Each event starts a clock that measures how long it takes us to turn that change into data our authoritative DNS servers can use. We call that work a build. A build reads the current database state, converts it into the format used at the edge, and writes any changes to Quicksilver.
In 2022, per-record builds were 150 times faster than full builds on average. On a test zone with one million records, per-record builds were 4,250 times faster. We ended that post with the obvious next step: do the same thing for zone settings.
Why doesn't the Zone Builder just rebuild the setting that changed?
It should, and that is where we ended up. However, proving when it was safe took most of the work. A record event identifies what changed. A zone event can come from many Cloudflare products, may not say why the zone changed, and can alter data shared by several zones with the same name. Choosing too much work wastes capacity. Choosing too little can leave stale or incorrect DNS data at the edge.
We built a targeted build planner that chooses the smallest build we can prove is safe, and a new scheduler that combines work for the same zone. Zone setting changes no longer rebuild zones with tens of millions of records. Together, they cut peak memory by 85%, and the extra headroom let us safely shorten waits the pipeline has always needed for resilience, halving the time from a DNS change to its data being written to Quicksilver.
How DNS changes reach the edge
A DNS zone is the collection of records and settings for a domain. Cloudflare uses a multi-stage pipeline to turn a change to that zone into data available across our global network.
- A customer changes a DNS record through the DNS Records API or dashboard, or another Cloudflare service changes a zone setting.
- The change is stored in a database.
- The database change or another system produces a Kafka event.
- The DNS Kafka Aggregator combines events from several Kafka topics and sends them to the Zone Builder.
- The Zone Builder reads the required zone data and converts it into keys understood by our authoritative DNS servers.
- The Zone Builder compares those keys with Quicksilver, our distributed key-value store. It writes only what changed, and Quicksilver propagates those changes across Cloudflare's network.
This is a simplified view. The Zone Builder does not copy database rows directly to the edge. It combines records with zone settings, applies DNS serving rules, and organizes the result so our authoritative DNS servers can read it quickly.
Why full builds stopped scaling
The original Zone Builder had one useful property: it did not need to know why a zone changed. It rebuilt the desired state from the current database state.
- Read the current zone and its settings.
- Read every DNS record in the zone.
- Convert those records into Quicksilver keys.
- Compare the new keys with those already stored.
- Remove stale keys, write changed keys, and update zone metadata.
The final write contains only changed keys. However, a full build still reads, encodes, and compares every record, and holds the whole zone in memory while it does so. That is cheap for a small zone. For our largest zones, with tens of millions of records, the zone does not fit in memory at all. I explain how we handle that below.
Zone settings made targeting harder. Universal SSL is one example. Enabling or disabling it updates metadata and can change Certification Authority Authorization (CAA) records at the zone apex, the bare domain, such as example.com. CAA records tell certificate authorities whether they may issue a certificate for the domain.
A full build only needed to know that the zone changed. A targeted build must answer three questions:
- Which DNS names can change?
- Can shared metadata or the list of published zones change?
- What previous state must be removed from Quicksilver?
Answering those questions safely meant solving five problems, which the rest of this post covers in order:
- Events had to say what changed.
- Each change had to map to the smallest build that is still correct.
- Builds had to account for data shared by every zone with the same name.
- The database could change between the event and the build.
- Combining work could not lose a Kafka message.
Making events say what changed
We changed the event producer to include changed zone fields and settings, with previous and new values when available. We then traced each setting through the code that generates DNS output and classified what it could affect.
Not every event was that specific. Some database functions only update a timestamp to say, in effect, "something about this zone changed." Sometimes that is harmless bookkeeping. Sometimes it means data changed elsewhere and must be read again.
Those cases look identical in the event. Until we can identify the caller and its purpose, a timestamp-only update still causes a full build. The same rule applies to missing details, unknown events, or any change that may affect records anywhere in the zone. The planner never turns uncertainty into less work.
Choosing the smallest safe build
Quicksilver output has two parts that matter here. Record keys contain the DNS answers for one zone and name. A smaller shared metadata key tells our authoritative DNS servers how to use that zone, including where to find special records such as nameservers and wildcards. Some events change only record keys; others must update both.
With that distinction, the planner can choose one of five build types:
- Resources only: Rebuild the records at specific DNS names, which we call resources, without changing zone metadata. Ordinary A, AAAA, TXT, and CNAME changes usually take this path.
- Resources and metadata: Rebuild specific names and shared metadata. Nameserver and wildcard changes use this path.
- Apex and metadata: Rebuild the zone apex and metadata. Settings such as Universal SSL can use this path.
- Purge: Remove a zone that should no longer be published.
- Full zone: Rebuild every record when smaller work cannot be proven safe.
The rule is simple: every key a targeted build writes must be byte-for-byte identical to what a full build would write. If we cannot prove that, we do a full build.
Removing old state works as it did for per-record builds in 2022. Record events include deleted records and the previous version of updated ones. The Zone Builder then scans Quicksilver for the existing keys under each name it rebuilds, removing any that the new build did not write.
Full builds remain necessary when a change can affect records anywhere in the zone or when a zone may need to be published for the first time.
There is one deliberate exception. A full build holds every record from the database and every existing Quicksilver key for the zone in memory at once, and our largest zones do not fit. Above a fixed record-count threshold, the Zone Builder never escalates to a full build. It rebuilds the apex, the metadata, and every name identified by the queued events instead. We accept this tradeoff because a full build of those zones cannot finish, and, while it retries, it holds back every other change on its Kafka partition. Many of the cases that would otherwise need a full build involve several zones sharing one name, and zone holds reduce that risk by stopping the same name from being added to another account. For the rare cases that remain, such as enabling a zone on another network, we can manually rebuild individual names in the zone.
When one name means more than one zone
Quicksilver stores each zone's record keys separately. It also stores one metadata key shared by every Cloudflare zone with that domain name. This shared key acts like a directory: it tells our authoritative DNS servers which internal zone IDs they may use when answering a query.
Why can one name have several zone IDs? During customer onboarding, offboarding, and other lifecycle changes, multiple Cloudflare zone objects can briefly exist for the same public domain. We use a priority policy to choose a small, bounded set to publish.
Consider four internal zones for example.com: Zone 101, Zone 202, Zone 303, and Zone 404. The metadata key currently lists Zones 101, 202, and 303. Zone 404 exists, but it is not selected. The numbers identify separate Cloudflare zone objects; customers still see one domain name.
A TXT record change at www.example.com in Zone 202 affects only Zone 202's record keys, so the metadata key does not change. Nameserver and wildcard changes are different because the metadata key records information about them. Those builds must update both the zone's records and the metadata key.
At execution time, the Zone Builder reads the current list again. If it writes the metadata key, it rebuilds the whole key from that fresh view rather than patching an older copy. It writes the triggering zone's records before the metadata that refers to them.
Planning from the event, verifying before writing
An event describes what happened in the past. A build may wait while more events arrive and the database changes, so planning happens twice. The event first creates a conservative work list. Immediately before execution, the Zone Builder reads a fresh publication snapshot: the current zone settings, whether this Zone Builder should publish the zone to its network, and which same-name zone IDs belong in the metadata key. Here, a network is a separate, isolated copy of Quicksilver for one environment. Each Zone Builder deployment writes to one network, and a zone can be enabled on some networks but not others. For example, a zone can be served from Cloudflare's global network and also from the China Network.
Fresh state can change the result in four ways:
- A targeted build can become a full build if the zone now has a feature that requires complete-zone work.
- A build can become a purge if the zone should no longer be published to this network.
- A build can be skipped if the triggering zone no longer belongs in the metadata key.
- A metadata build can reconstruct the shared key from the current candidate set.
The fresh read comes from read-only copies of the database, called replicas, so builds do not compete with customer writes. Kafka delivery and database replication move independently: an event can arrive before its database change is visible on a replica. The DNS Kafka Aggregator delays events long enough to cover normal lag, and a final database check rejects the read if that replica is still behind.
Combining changes in one scheduler
Record work and full-zone work previously used different schedulers. Each could combine its own work, but not work from the other scheduler. We replaced them with one unified scheduler. The planner decides what must be built, and the scheduler decides when it can run.
When several events for one zone arrive before a build starts, the scheduler combines their work:
- An A record changes at
www.example.com, requiring that name. - A wildcard changes at
*.example.com, requiring that name and shared metadata. - The scheduler combines both names and the metadata update into one build.
Merging only adds work. If any event requires the complete zone, the combined build becomes a full build. A purge overrides every rebuild because its desired result is that the zone is no longer published.
The scheduler tracks two things separately: the DNS work that must be performed and the Kafka messages waiting to be acknowledged. A retry preserves both. Even when a full build or purge no longer needs the individual record names, the messages stay attached until the result is safely written.
Keeping Kafka moving
One slow build can delay unrelated customers even when workers are available. Kafka divides messages into ordered partitions. For each partition, it stores one committed offset: the point before which every message is known to be complete. Moving that offset past unfinished work could lose a customer change after a restart.
We use soft committing, which I previously described in my Secondary DNS deep dive. A build can finish out of order and be marked complete in memory, but Kafka's committed position advances only after every earlier message has also finished.
In the diagram, message 2 is still running, so messages 3 through n cannot be committed. If the Zone Builder restarts, those in-memory completions disappear and Kafka replays messages 2 through n. We deliberately choose repeated work over losing a change.
Targeted plans reduce how long the oldest message stays unfinished. The scheduler also prevents one busy zone from taking every worker. After a zone builds, its next build waits for a per-zone rebuild interval, which differs by Cloudflare plan. Changes that arrive in the meantime are merged into that next build. The scheduler normally enforces this interval, but lets old queued work run before it blocks a Kafka partition for too long. Zone locks and retry delays still apply, so a failing build cannot run in a tight loop.
Releasing safely
A smaller build is useful only if it produces the same DNS data. We added equivalence tests for nameserver, wildcard, and apex paths. Each test runs a full build and a targeted build from the same database state, pins time-dependent values, and compares every Quicksilver key owned by the targeted plan byte for byte. Planner and scheduler tests cover classification, same-name zones, merging, purges, and escalation.
During rollout, we also ran a full build next to every targeted build and compared the output. It was expensive by design, reading the complete zone every time, so we used it only until the mirror comparison below gave us the same confidence.
Tests cannot reproduce every customer combination, so every release also runs through a mirror Zone Builder. It consumes the production Kafka stream and reads production database state, but writes to a separate Quicksilver environment that serves no customer traffic.
A comparer checks a 20% sample of zones for missing keys, extra keys, and different values. The two environments do not always build a zone at the same instant, so a temporary mismatch is not automatically a regression. We look for new types of differences that remain after both pipelines catch up. That gives us confidence that targeted builds produce the same output as production.
We built the DNS Mirror Dashboard to group those differences and keep examples for investigation. Naturally, it runs on the Cloudflare Developer Platform: a Worker receives results, Durable Objects maintain state, and Cloudflare Access protects it. The critical groups in the screenshot below were each checked and confirmed safe before release. The diff rate is the share of compared zones where production and mirror disagreed on at least one key at the moment of comparison. Most of those are timing differences that disappear once both pipelines catch up, so we watch two things: that the rate stays low, and that no new kind of difference appears.
After the mirror results remained healthy, we rolled the scheduler out by a hash of the zone name. Hashing the name rather than the zone ID kept every zone sharing a name on the same scheduler, so two schedulers never wrote the same metadata key. We increased the percentage for free zones, then repeated the process for paid zones.
Results
Over 24 hours, we measured 86.81% of builds as resources only, 2.54% as resources and metadata, 2.30% as apex and metadata, and 1.30% as purges. Together, 92.95% of builds avoided rebuilding the complete zone. Full builds were the remaining 7.04%.
The two metadata build types were full builds before, even for large zones. Together, they account for 4.84% of builds. Combined with the 7.04% that are still full builds, that is 11.88%, so full builds fell by about 40%. Their share of the count also understates the work avoided, because they include the largest zones. The full builds that remain average 0.35 seconds, because the events that still trigger them, such as a zone being published for the first time, mostly affect new zones with few records.
In 2022, we also planned a batching system. The unified scheduler makes it unnecessary: it does not wait to form batches, and it merges events only when work is already queued for the same zone. Before, long full builds held back the committed offset for their partition. With fewer of them, we now consume Kafka at the rate events arrive, instead of falling behind and catching up in bursts of up to 1,550 messages per second.
We also measured build completion delay: the time from a DNS record or zone setting change until the Zone Builder finished writing to Quicksilver. It does not include Quicksilver's distribution across our network, which varies by location and is unaffected by this work. Production ran the old schedulers, and the mirror ran the unified scheduler on the same events over the same 24 hours. The two environments are identical apart from the code: they consume the same Kafka events, read from the same database, and write equivalent data to Quicksilver. That makes this a controlled, side-by-side comparison. The figures combine every build type and customer plan, so they are not a latency guarantee for an individual zone. A large share of this time is the rebuild interval described earlier, not build work. At each measurement point, p99 is the time within which 99% of events finished. Typical delays barely changed here, because most builds were already small. The difference is in the tail: the largest p99 spike fell from 14.6 minutes to 1.21 minutes, a 12-fold reduction. The chart uses a logarithmic scale.
Targeted builds also load complete large zones far less often. Aggregate working-set memory, the memory actively used by the deployment, fell from an average of 49 GiB to 7 GiB, an 86% reduction. Peaks fell from 79 GiB to 12 GiB, an 85% reduction.
Those were the immediate results of the new scheduler. They also let us revisit two safeguards. The first is the rebuild interval, which stops one busy zone from rebuilding constantly and taking capacity from everyone else. With builds now cheaper, and far fewer of them reading complete zones, we could safely shorten that interval on most plans. The second is how long the DNS Kafka Aggregator holds each event, to make sure database replicas have caught up before we read from them. Once our databases began rejecting reads from replicas that had fallen behind, that buffer could safely be smaller. Together, these halved the median build completion delay, from about 7.7 seconds to about 3.3 seconds. In the chart below, the first step down is the DNS Kafka Aggregator change. The red band marks the Zone Builder release with shorter rebuild intervals. That release rolled out gradually across our servers, so the delay falls in two further steps rather than all at once.
The p90 and p99 lines in that chart are less precise than they look. The histogram had buckets at 1, 5, 10, and 30 seconds, and a percentile that falls between two edges is estimated as if delays were spread evenly across that range. Most delays sit near the bottom of their range, so those estimates come out high: p99 reads close to 30 seconds, and p90 above 7 seconds. The exact average, which does not depend on buckets, confirms the halving. We have since switched to a native histogram, which chooses fine-grained buckets automatically. It puts p90 at about 5.5 seconds and p99 at about 12 seconds.
Why full builds still exist
In 2022, we said we planned to eliminate full builds entirely. We now know that is neither realistic nor useful. A zone being published for the first time needs every record written. A change that can affect records anywhere in the zone needs every record checked. An event that does not say what changed still gets a full build, because the planner never turns uncertainty into less work. For a small zone, a full build is also cheap.
As we learn what more events change, we will keep moving them to targeted builds. However, the biggest gain has already landed: the events that used to rebuild our largest zones no longer do, and the full builds that remain are mostly triggered by events, such as first publication, that affect new, small zones.
Want to know what happens after the Zone Builder writes a change? Read how Quicksilver distributes configuration to every Cloudflare data center in seconds.
The Great Paris Flood of 1910
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=djEqjQpr7eI
AI Vulnerability Finding
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/11/ai-vulnerability-finding-2.html
A comment:
3% of ‘critical’ software security bugs, in all of recorded history, have been found in the last month. This is on pace to find another ~100,000 bugs this year alone, adding ~26% more vulnerabilities to the all time total Do you realize how fucking insane that is?
Yes. It is a new world out there.
Midterms 2026: Last Week Tonight with John Oliver (HBO)
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=Np7_mlvXFcA
S13 E28: Midterm Elections & The $100 Bill: 11/1/26: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=Lz-QkCnw6WQ
Liquid-Cooled NVIDIA Servers at the ASRock Rack OCP 2026 Booth
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/liquid-cooled-nvidia-servers-at-the-asrock-rack-ocp-2026-booth/
We checked out the ASRock Rack booth at OCP 2026 and saw servers ranging from fully integrated NVIDIA NVL72 racks to liquid-cooled switches
The post Liquid-Cooled NVIDIA Servers at the ASRock Rack OCP 2026 Booth appeared first on ServeTheHome.
Inside a successful AWS European Sovereign Cloud exercise to demonstrate independent operation
Post Syndicated from Stéphane Israël original https://aws.amazon.com/blogs/security/inside-a-successful-aws-european-sovereign-cloud-exercise-to-demonstrate-independent-operation/
On Saturday, October 24, 2026 we conducted a successful exercise demonstrating that the AWS European Sovereign Cloud can operate without depending on any infrastructure outside the European Union (EU). This was the first public technical exercise demonstrating the independence of a sovereign cloud Region.
The AWS European Sovereign Cloud is a new, independent cloud partition for Europe that became generally available in January 2026, with its first AWS Region in Brandenburg, Germany. It is physically and logically separate from other AWS Regions, with no critical dependencies on non-EU infrastructure, and all customer content and customer-created metadata remains in the EU.
The AWS European Sovereign Cloud is managed through dedicated European legal entities established under German law and operated entirely within Europe. My fellow Managing Director, Stefan Hoechbauer, and I called for the exercise. We are EU citizens residing in the EU, responsible for its management and operations, including its infrastructure, technology, and services. Only EU residents located in the EU control its operations and support, and AWS is gradually transitioning the AWS European Sovereign Cloud to be operated exclusively by EU citizens located in the EU.
What we did
In standard operations, the AWS European Sovereign Cloud uses two global systems: the AWS Global Network backbone, and a dedicated system operated by the local EU team to manage limited, controlled transfers of operational AWS data. As we explained ahead of the exercise, neither is critical to running the AWS European Sovereign Cloud. During the exercise, the team switched off both systems, and traffic that normally travels across the AWS Global Network backbone rerouted securely over the public internet.
The AWS European Sovereign Cloud can operate independently at any time, and for several hours on October 24 the team showed exactly that, running it on only its own software and hardware resources, operated by EU-resident staff within the EU.
Workloads continued running, and customers could still access their data. The exercise did not affect service availability within the AWS European Sovereign Cloud, other AWS Regions, or private connectivity through AWS Direct Connect. When the exercise finished, traffic returned to its normal path.
Why we ran it
Transparency is at the core of our digital sovereignty commitment, so we ran the AWS European Sovereign Cloud exercise openly and reported back on the outcome.
The exercise produced verifiable technical and operational evidence that the AWS European Sovereign Cloud can continue to operate independently within the EU. It turns a design claim into a verified result. Organizations in regulated industries and the public sector can take this result to regulators and their boards as evidence for their compliance and assurance documents.
What customers and partners are saying
“Digital sovereignty is ultimately about trust and safeguarding business continuity. The successful demonstration of the AWS European Sovereign Cloud’s operational independence is an important proof point for European organizations with the most stringent sovereignty requirements. Combined with Capgemini’s European heritage, presence and AWS capabilities, we can deliver a sovereign proposition in Europe, for Europe, by Europeans, enabling clients to accelerate secure and resilient cloud and AI transformation at scale whilst assuring business continuity.” – Fernando Alvarez, Chief Strategy and Development Officer and Group Executive Board Member, Capgemini
“Autonomy, resilience and operational control are foundations driving digital sovereignty concerns across the public sector and regulated industries. Achieving sovereignty requires more than a sound and consistent architecture; it demands operational evidence to build trust. The AWS European Sovereign Cloud team has provided evidence, supporting organizations on the transformation of their critical data and digital assets toward greater sovereign control. Having engaged with this team since the inception of the project, and as a Launch Partner of the AWS Digital Sovereignty Competency, Atos helps customers define their sovereignty roadmaps, adopt the appropriate graduated solutions, and confidently operate and govern their target sovereignty posture.” – Michael Kollar, Digital Sovereignty Leader and Head of Cloud & Modern Infrastructure and Digital Workplace, Atos Group
“For organizations in regulated industries, meeting strict data and operational requirements cannot come at the cost of a great customer experience. Running on the AWS European Sovereign Cloud, Genesys can help European organizations deliver exactly that, with their data and operations kept in the EU. Seeing the AWS European Sovereign Cloud operate independently under real conditions helps give our shared customers added confidence to move their most sensitive workloads to the cloud.” – Daniel Karadza, Senior Director, Partners and Alliances, EMEA Central and Benelux, Genesys
“Operational independence is a defining pillar of digital sovereignty, and the AWS European Sovereign Cloud has shown what that means in practice. It runs without reliance on any infrastructure outside the EU and is operated entirely by EU residents, which makes it a strong fit for Europe’s regulated industries and public sector. As an early collaborator with the AWS European Sovereign Cloud team before its launch, Accenture is uniquely positioned to help clients navigate sovereignty requirements and scale with greater confidence and control.” – Emanuele Baldassarre, Managing Director, Accenture
Learn more
To learn more about the design and digital sovereignty controls of the AWS European Sovereign Cloud, visit aws.eu. If you have questions about this exercise or want to discuss your workloads, reach out to AWS Support or contact your AWS Account team.
Kernel prepatch 7.4-rc1
Post Syndicated from corbet original https://lwn.net/Articles/1104654/
The 7.4-rc1 kernel prepatch is out, and
the merge window is closed for this development cycle.
This is a *BIG* merge window. I think the reason is the by now
obvious one, but I’m actually taking it as a good sign: I’m *much*
happier with the flood of AI triggered work going into the merge
window than it showing up mainly as extra fixes during the -rc
period. So I’m hoping that this merge window being larger than
usual is a sign that the AI fixes are becoming more part of the
“normal development” than a flood of fixes that go into the whole
stabilization phase. I think that’s a much healthier model.
There were 18,591 non-merge changesets brought in during this merge window
— this is not just a record, but it nearly matches the patch volume during
the entire (record-setting) 7.3 development cycle. So far, 2,678
developers have contributed to 7.4; 625 of them are first-time kernel
contributors. Subscribers can find more details in the KSDB 7.4 page.
Comic for 2026.11.02 – Dancer
Post Syndicated from Explosm.net original https://explosm.net/comics/dancer
New Cyanide and Happiness Comic