June 2025 marks the 11th anniversary of Project Galileo, Cloudflare’s initiative to provide free cybersecurity protection to vulnerable organizations working in the public interest around the world. From independent media and human rights groups to community activists, Project Galileo supports those often targeted for their essential work in human rights, civil society, and democracy building.
A lot has changed since we marked the 10th anniversary of Project Galileo. Yet, our commitment remains the same: help ensure that organizations doing critical work in human rights have access to the tools they need to stay online. We believe that organizations, no matter where they are in the world, deserve reliable, accessible protection to continue their important work without disruption.
For our 11th anniversary, we’re excited to share several updates including:
An interactive Cloudflare Radar report providing insights into the cyber threats faced by at-risk public interest organizations protected under the project.
An expanded commitment to digital rights in the Asia-Pacific region with two new Project Galileo partners.
New stories from organizations protected by Project Galileo working on the frontlines of civil society, human rights, and journalism from around the world.
Tracking and reporting on cyberattacks with the Project Galileo 11th anniversary Radar report
To mark Project Galileo’s 11th anniversary, we’ve published a new Radar report that shares data on cyberattacks targeting organizations protected by the program. It provides insights into the types of threats these groups face, with the goal of better supporting researchers, civil society, and vulnerable groups by promoting the best cybersecurity practices. Key insights include:
Our data indicates a growing trend in DDoS attacks against these organizations, becoming more common than attempts to exploit traditional web application vulnerabilities.
Between May 1, 2024, to March 31, 2025, Cloudflare blocked 108.9 billion cyber threats against organizations protected under Project Galileo. This is an average of nearly 325.2 million cyber attacks per day over the 11-month period, and a 241% increase from our 2024 Radar report.
Journalists and news organizations experienced the highest volume of attacks, with over 97 billion requests blocked as potential threats across 315 different organizations. The peak attack traffic was recorded on September 28, 2024. Ranked second was the Human Rights/Civil Society Organizations category, which saw 8.9 billion requests blocked, with peak attack activity occurring on October 8, 2024.
Cloudflare onboarded the Belarusian Investigative Center, an independent journalism organization, on September 27, 2024, while it was already under attack. A major application-layer DDoS attack followed on September 28, generating over 28 billion requests in a single day.
Many of the targets were investigative journalism outlets operating in regions under government pressure (such as Russia and Belarus), as well as NGOs focused on combating racism and extremism, and defending workers’ rights.
Tech4Peace, a human rights organization focused on digital rights, was targeted by a 12-day attack beginning March 10, 2025, that delivered over 2.7 billion requests. The attack saw prolonged, lower-intensity attacks and short, high-intensity bursts. This deliberate variation in tactics reveals a coordinated approach, showing how attackers adapted their methods throughout the attack.
The full Radar report includes additional information on public interest organizations, human and civil rights groups, environmental organizations, and those involved in disaster and humanitarian relief. The dashboard also serves as a valuable resource for policymakers, researchers, and advocates working to protect public interest organizations worldwide.
Global partners are the key to Project Galileo’s continued growth
Partnerships are core to Project Galileo success. We rely on 56 trusted civil society organizations around the world to help us identify and support groups who could benefit from our protection. With our partners’ help, we’re expanding our reach to provide tools to communities that need protection the most. Today, we’re proud to welcome two new partners to Project Galileo who are championing digital rights, open technologies, and civil society in Asia and around the world.
EngageMedia is a nonprofit organization that brings together advocacy, media, and technology to promote digital rights, open and secure technology, and social issue documentaries. Based in the Asia-Pacific region, EngageMedia collaborates with changemakers and grassroots communities to protect human rights, democracy, and the environment.
As part of our partnership, Cloudflare participated in a 2025 Tech Camp for Human Rights Defenders hosted by EngageMedia, which brought together around 40 activist-technologists from across Asia-Pacific. Among other things, the camp focused on building practical skills in digital safety and website resilience against online threats. Cloudflare presented on common attack vectors targeting nonprofits and human rights groups, such as DDoS attacks, phishing, and website defacement, and shared how Project Galileo helps organizations mitigate these risks. We also discussed how to better promote digital security tools to vulnerable groups. The camp was a valuable opportunity for us to listen and learn from organizations on the front lines, offering insights that continue to shape our approach to building effective, community-driven security solutions.
Founded in 2014 by leaders of Taiwan’s open tech communities, the Open Culture Foundation (OCF) supports efforts to protect digital rights, promote civic tech, and foster open collaboration between government, civil society, and the tech community. Through our partnership, we aim to support more than 34 local civil society organizations in Taiwan by providing training and workshops to help them manage their website infrastructure, address vulnerabilities such as DDoS attacks, and conduct ongoing research to tackle the security challenges these communities face.
Stories from the field
We continue to be inspired by the amazing work and dedication of the organizations that participate in Project Galileo. Helping protect these organizations and allowing them to focus on their work is a fundamental part of helping build a better Internet. Here are some of their stories:
Fair Future Foundation (Indonesia): non-profit that provides health, education, and access to essential resources like clean water and electricity in ultra-rural Southeast Asia.
Youth Initiative for Human Rights (Serbia): regional NGO network promoting human rights, youth activism, and reconciliation in the Balkans.
Belarusian Investigative Center (Belarus): media organization that conducts in-depth investigations into corruption, sanctions evasion, and disinformation in Belarus and neighboring regions.
The Greenpeace Canada Education Fund (GCEF) (Canada): non-profit that conducts research, investigations, and public education on climate change, biodiversity, and environmental justice.
Insight Crime (LATAM): nonprofit think tank and media organization that investigates and analyzes organized crime and citizen security in Latin America and the Caribbean.
Diez.md (Moldova): youth-focused Moldovan news platform offering content in Romanian and Russian on topics like education, culture, social issues, election monitoring and news.
Engage Media (APAC): nonprofit dedicated to defending digital rights and supporting advocates for human rights, democracy, and environmental sustainability across the Asia-Pacific.
Pussy Riot (Europe): a global feminist art and activist collective using art, performance, and direct action to challenge authoritarianism and human rights violations.
Immigrant Legal Resource Center (United States): nonprofit that works to advance immigrant rights by offering legal training, developing educational materials, advocating for fair policies, and supporting community-based organizations.
5wf Foundation (Netherlands): wildlife conservation non-profit that supports front-line conservation teams globally by providing equipment to protect threatened species and ecosystems.
These case studies offer a window into the diverse, global nature of the threats these groups face and the vital role cybersecurity plays in enabling them to stay secure online. Check out their stories and more: cloudflare.com/project-galileo-case-studies/
Continuing our support of vulnerable groups around the world
In 2025, many of our Project Galileo partners have faced significant funding cuts, affecting their operations and their ability to support communities, defend human rights, and champion democratic values. Ensuring continued support for those services, despite financial and logistical challenges, is more important than ever. We’re thankful to our civil society partners who continue to assist us in identifying groups that need our support. Together, we’re working toward a more secure, resilient, and open Internet for all. To learn more about Project Galileo and how it supports at-risk organizations worldwide, visit cloudflare.com/galileo.
In the fast-paced world of data analytics, real-time processing has become a necessity. Modern businesses require insights not just quickly, but in real-time to make informed decisions and stay ahead of the competition. Apache Flink has emerged as a powerful tool in this domain, offering state-of-the-art stream processing capabilities. In this blog, we introduce our FlinkSQL interactive solution in accompanying productionising automation, and enhancing our users’ stream processing development journey.
Preface
Last year, we introduced Zeppelin notebooks for Flink, as detailed in our previous post Rethinking Stream Processing: Data Exploration in an effort to enhance data exploration for downstream data users. However, as our use cases evolved over time, we quickly hit a few technical roadblocks.
Flink version maintenance
Zeppelin notebook source code is maintained by a community separate from Flink’s community. As of writing, the latest Flink version supported is 1.17, whilst the latest Flink is already on version 1.20. This discrepancy in version support hinders our Flink upgrading efforts.
Cluster start up time
Our design to spin up a Zeppelin cluster per user on demand invokes a cold start delay, taking roughly around 5 minutes for the notebook to be ready. This delay is not suitable for use cases that require quick insights from production data. We quickly noticed that the user uptake of this solution was not as high as we expected.
Integration challenges
Whilst Zeppelin notebooks were useful for serving individual developers, we experienced difficulty integrating it with other internal platforms. We designed Zeppelin to empower solo data explorers, but other internal platforms like dashboards or automated pipelines needed a way to aggregate data from Kafka and Zeppelin just couldn’t keep up. The notebook setup was too isolated, requiring a workaround to share insights or plug into existing tools. For instance, if a team wanted to pull aggregated real-time metrics into a monitoring system, they had to export data manually, which is far from seamless access that we aimed for.
Introducing FlinkSQL interactive
With those considerations in mind, we decided to swap out our Zeppelin cluster with a shared FlinkSQL gateway cluster. We simplified our solution by removing some features our notebooks offered, focusing only on features that promote data democratisation.
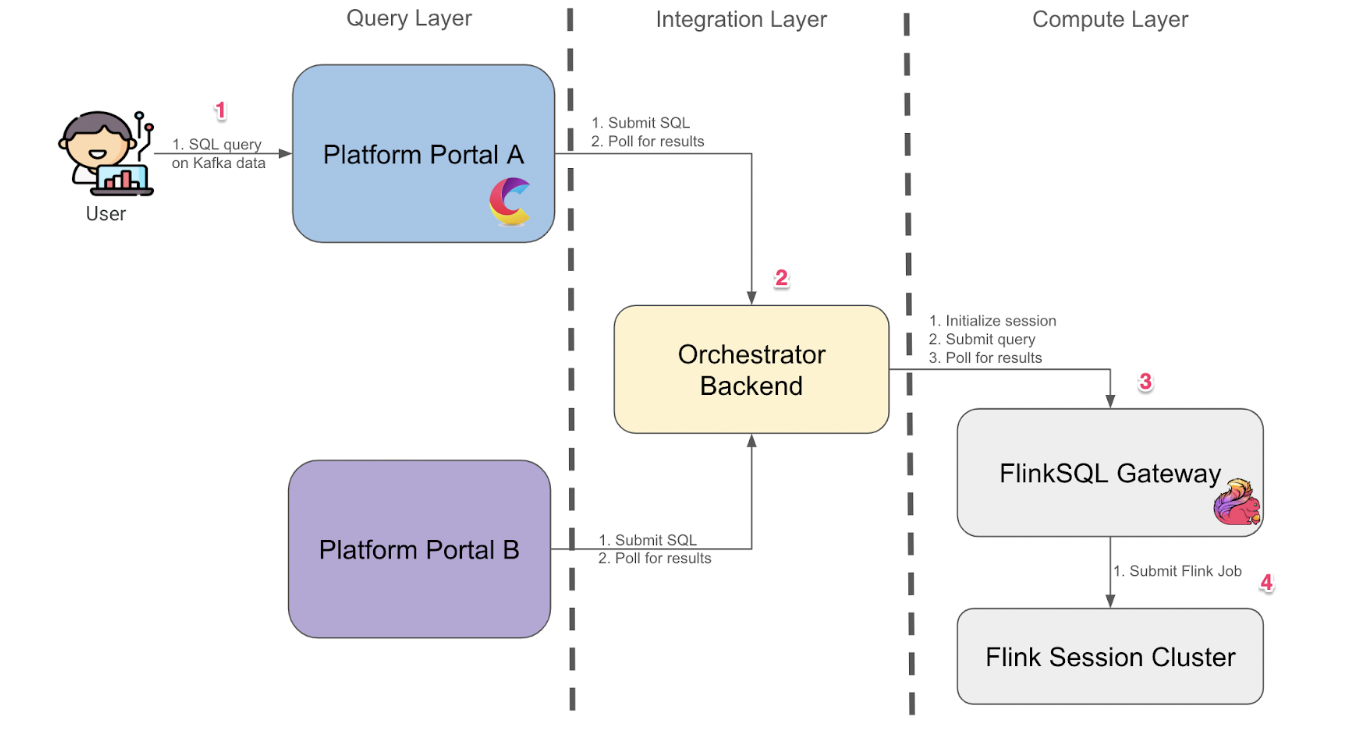
Figure 1: Shared FlinkSQL gateway architecture
We split our solution into 3 layers:
Compute layer
Integration layer
Query layer
Users first interact with our platform portal to submit queries for data from Kafka online store using SQL (1). Upon submission, our backend orchestrator then creates a session for the user (2) and submits the SQL query to our FlinkSQL gateway using their inbuilt REST API (3). The FlinkSQL gateway then packages the SQL query into a Flink job to be submitted to our Flink session cluster (4) before collating its results. The subsequent results would be polled from the query layer to be displayed back to the user.
Compute layer
With FlinkSQL gateway acting as the main compute engine for ad-hoc queries, it is now more straightforward to perform Flink version upgrades along with our solution, since the FlinkSQL gateway is packaged along with the main Flink distribution. We do not need to maintain Flink shims for each version as adapters between the Flink compute cluster and Zeppelin notebook cluster.
Another advantage of using the shared FlinkSQL gateway was the reduced cold start time for each ad-hoc queries. Since all users share the same FlinkSQL cluster instead of having their own Zeppelin cluster, there was no need to wait for cluster startup during initialisation of their sessions. This brought the lead time to the first results displayed down from 5 minutes to 1 minute. There was still lead time involved as the tool provisions task managers on an ad-hoc basis to balance availability of such developer tools and the associated cost.
Integration layer
The Integration layer serves as the glue between the user-facing query layer and the underlying compute layer, ensuring seamless communication and security across our ecosystem. With the shift to a shared FlinkSQL gateway, we recognised the need for an intermediary that could handle authentication, authorisation, orchestration, and integration with internal platforms – all while abstracting the complexities of Flink’s native REST API.
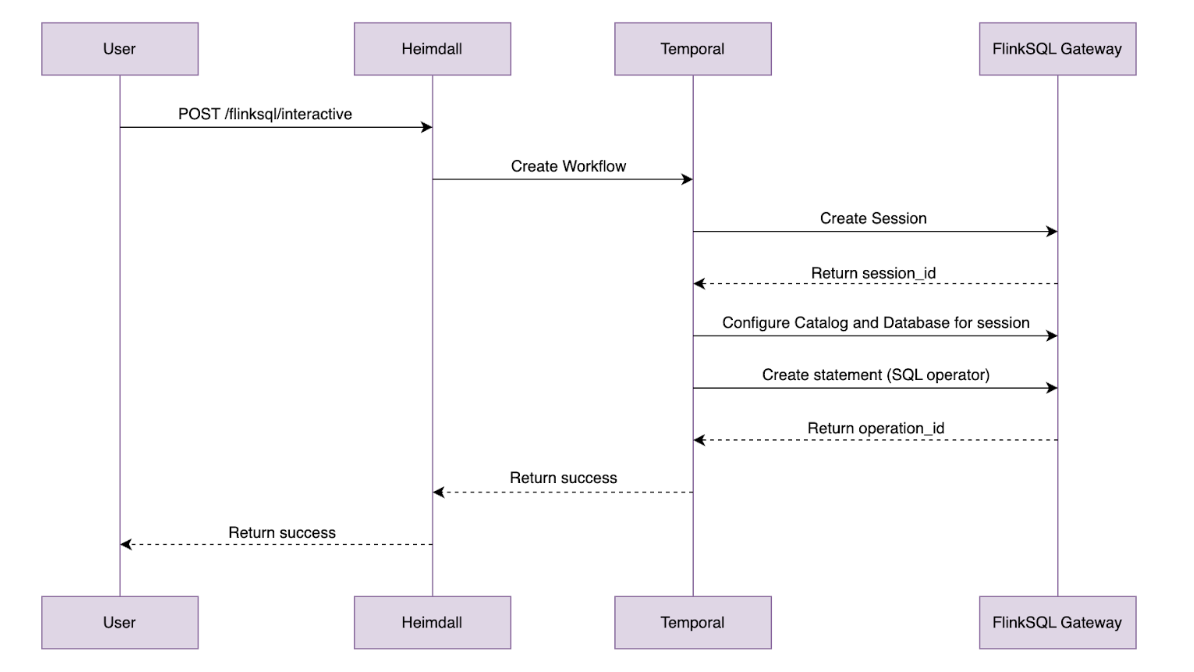
Figure 2: FlinkSQL gateway
The FlinkSQL gateway’s built-in REST API gets the job done for basic query submission, but it falls short in areas like session management, requiring multiple POST requests just to fetch results. To address this, we extended a custom control plane with its own set of REST APIs, layered on top of the gateway.
We then extend these sessions and integrate them to our inhouse authentication and authorisation platform. For each query made, the control plane authenticates the user, spins up lightweight sessions and manages the communication between the caller and the Flink Session Cluster. If you are interested, check out our previous blog post, An elegant platform, for more details on the above mentioned streaming platform and its control plane.
The integration layer also caters to B2B needs via our Headless APIs. By exposing the endpoints, developers are able to integrate real-time processing into their own tools. To run a query, programs can simply make a POST request with the SQL query and an operation ID would be returned. This operation ID could then be used in subsequent GET requests to fetch the paginated results of the unbounded query. This setup is ideal for internal platforms that need to query Kafka data programmatically. By abstracting these complexities, it ensures that users, whether individual analysts or internal platforms—can tap into Kafka data without wrestling with Flink’s raw interfaces.
Query layer
We then proceed to pair our APIs developed with an Interactive UI to build a Query layer that serves both human workflows. This is where users meet our platform.
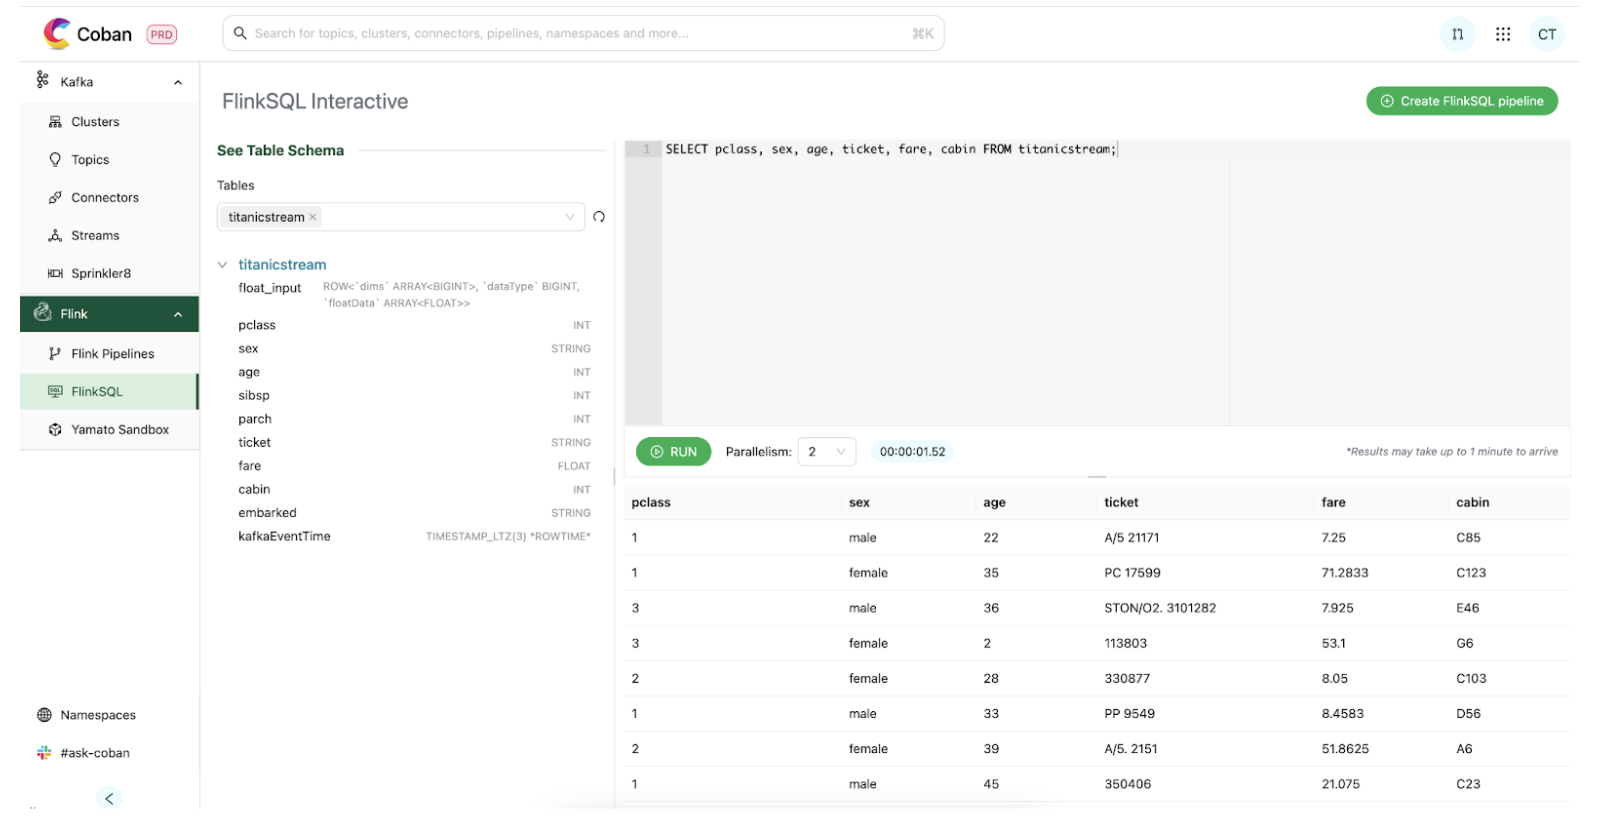
Figure 3: Flink query layer’s user flow
Through our platform portal, users land in a clean SQL editor. We used a Hive Metastore (HMS) catalog that translates Kafka topics into tables. Users don’t need to decode stream internals; they can jump straight into it by simply selecting a table to query on. Once a query is submitted, it is then handled by the integration layer which routes it through the control plane to the gateway. Results are then streamed back, appearing in the UI within one minute, a significant improvement from the five minute Zeppelin cold starts.
This all crystalises into the user flow demonstrated in Figure 3, where we can easily retrieve Titanic data from a Kafka stream with a short command:
SELECT COUNT(*) FROM titanicstream WHERE kafkaEventTime > NOW() - INTERVAL '1' HOUR.
This setup enables a few use cases for our teams, such as:
Fraud analysts using the real-time data to debug and spot patterns in fraudulent transactions.
Data scientists querying live signals to validate their prediction models.
Engineers validating the messages sent from their system to confirm they are properly structured and accurately delivered.
Productionising FlinkSQL
With data being democratised, we see more users building use cases around our online data store and utilising the above tools to build new stream processing pipelines expressed as SQL queries. To simplify the last step of the software development lifecycle of deployment, we have also developed a tool to create a configuration based stream processing pipeline, with the business logic expressed as a SQL statement.
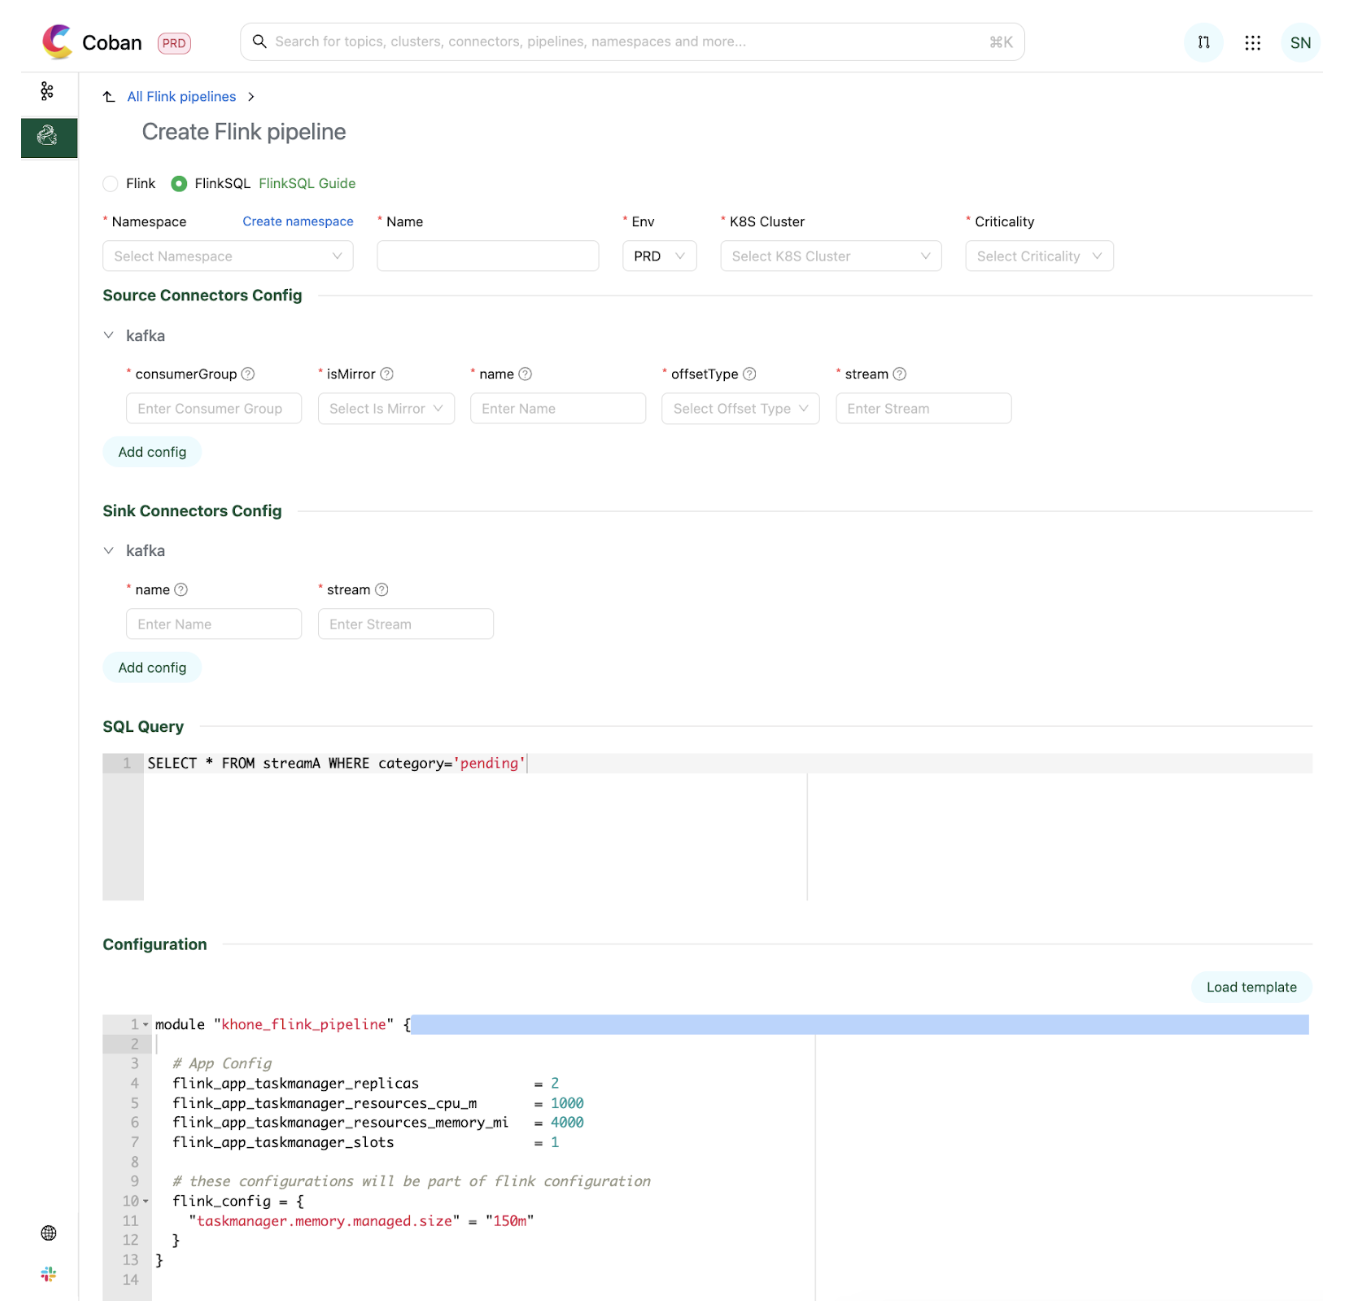
Figure 4: Portal for FlinkSQL pipeline creation
We host connectors for users to connect to other platforms within Grab, such as Kafka and our internal feature stores. Users could simply use them off-the-shelf and configure according to their needs before deploying their stream processing pipeline.
Users would then proceed to submit their streaming logic as a SQL statement. In the example illustrated in the diagram, the logic expressed is a simple filter on a Kafka stream for sinking the filtered events into a separate Kafka stream.
Users have the ability to then define the parallelism and associated resources they want to run their Flink jobs with. Upon submission, the associated resources would be provisioned and the Flink pipeline would be automatically deployed. Behind the scenes, we manage the application JAR file that is being used to run the job that dynamically parses these configurations and translates them into a proper Flink job graph to be submitted to the Flink cluster.
Within 10 minutes, users would have completed deploying their stream processing pipeline to production.
Conclusion
With our full suite of solutions for low code development via FlinkSQL, from exploration and design, to development and then deployment, we have simplified the journey for developing business use cases off online streaming stores. By offering both a user-friendly interface for low-code users and a robust API for developers, these tools empower businesses to harness the full potential of real-time data processing. Whether you are a data analyst looking for quick insights or a developer integrating real-time analytics into your applications, our tools are able to lower the barrier of entry to utilising real-time data.
After we released these solutions, we quickly saw an uptick in pipelines created as well as the number of interactive queries fired. This result was encouraging and we hope that this would gradually bring upon a paradigm shift, enabling Grab to make data-driven operational decisions on real-time signals, empowering us with the ability to react to ever-changing market conditions in the most efficient manner.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Managing AWS End User Messaging SMS registrations can be challenging, especially when dealing with multiple registrations in various states and countries. This post introduces an automated monitoring solution that helps you stay on top of your registration statuses. By leveraging AWS Lambda, EventBridge, and Simple Email Service (SES), you’ll create a system that provides regular updates about registrations that need attention, are under review, in draft pending submission, or have recently been completed.
Whether you’re managing Sender IDs, United States 10DLC campaigns, toll-free numbers, or short codes, this solution will help you maintain visibility across all your registrations and respond promptly to status changes. The setup takes approximately 15-20 minutes and requires no ongoing maintenance beyond occasional adjustments to meet your evolving needs.
Estimated Setup Time: 15-20 minutes
Prerequisites
An AWS account with access to Lambda, IAM, EventBridge, End User Messaging SMS, and SES
A verified email address in Amazon SES for sending reports.
Figure 1: AWS End User Messaging SMS registrations in the console. This view shows registrations in various states that our Lambda function will monitor.
Step 1: Set up Amazon SES
Open the Amazon SES console
Navigate to “Verified identities”
If you have an identity verified you can skip this section
If you do not already have an identity verified Click “Create identity”
Review this post to learn how to verify an identity NOTE: Best practice is to verify a domain identity. This will authenticate your domain and improve deliverability. An email address identity, while more simple, will not be authenticated through DKIM which may decrease deliverability.
Name your rule (e.g., “EndUserMessagingRegistrationsMonitorSchedule”)
For the event pattern, choose “Schedule” then select “Continue in EventBridge Scheduler”
Configure your schedule pattern to your requirements (for example, Cron-based schedule to run at specific days and times or rate-based schedule such as every 1 day). Click “Next”.
Select “Lambda” for “Target detail” and select the Lambda function created in Step 3 as the target from the dropdown. Click “Next”.
For permissions:
Select “Create new role for this schedule”
EventBridge will automatically create a role with the necessary permissions to invoke your Lambda function
Figure 2: The generated email report provides a clear summary of all registrations, categorized by their status.
Understanding the Lambda Function
Let’s break down the key components of our Lambda function:
Initialization: The script sets up necessary AWS clients and defines constants.
categorize_registrations(): This function fetches all registrations and categorizes them based on their status and type.
generate_html_output(): Creates a formatted HTML report of the registration statuses.
send_email(): Uses Amazon SES to send the HTML report via email.
lambda_handler(): The main entry point for the Lambda function, orchestrating the entire process.
The function categorizes registrations into four main statuses:
REQUIRES_UPDATES: Registrations that need attention or modifications
CREATED: Newly created registrations
REVIEWING: Registrations currently under review
COMPLETED: Registrations that have been approved recently (within the last 7 days by default)
Figure 3: Detailed view of a registration requiring updates and created registrations pending submission, including specific denial reasons if applicable and direct console links.
Customization Options
Lookback Period: Modify the COMPLETED_LOOKBACK_DAYS constant to change how far back the function checks for completed registrations.
Email Formatting: Adjust the HTML and CSS in generate_html_output() to customize the email report’s appearance.
Additional Data: Modify the reg_info dictionary in categorize_registrations() to include more data fields in your report.
Monitoring and Maintenance
CloudWatch Logs: Regularly check the Lambda function’s CloudWatch Logs for any errors or unexpected behavior.
Adjusting Schedule: If you find the current schedule doesn’t meet your needs, adjust the EventBridge rule accordingly.
Conclusion
You now have an automated system that monitors your End User Messaging SMS registrations and sends you regular, detailed status reports. This setup provides:
Automated visibility into registrations requiring updates or attention
Clear tracking of draft registrations awaiting your submission
Monitoring of registrations under review
Notifications of recently completed registrations
A consolidated view of all registration states through formatted email reports
This automated solution eliminates the need for manual status checking and helps ensure timely responses to registration changes. As your messaging needs grow, you can easily customize the monitoring frequency, lookback period, and report format to match your requirements.
Next Steps:
Consider adjusting the EventBridge schedule based on your registration volume
Customize the email format to highlight information most relevant to your team
Set up CloudWatch alarms to monitor the Lambda function’s health
Review and update the completed registrations lookback period as needed
For more complex scenarios, consider extending this solution with additional features like Slack notifications, registration metrics tracking, or integration with your ticketing system.
The All Systems Go! 2025 Call for Participation Closes Tomorrow!
The Call for Participation (CFP) for All Systems Go!
2025 will close tomorrow, on 13th of
June! We’d like to invite you to submit your proposals for
consideration to the CFP submission
site quickly!
We’re excited to announce that our Europe (London) AWS Region has renewed its accreditation for United Kingdom (UK) Police-Assured Secure Facilities (PASF) for Official-Sensitive data. Since 2017, the Amazon Web Services (AWS) Europe (London) Region has been accredited under the PASF program. This demonstrates our continuous commitment to adhere to the heightened expectations of customers with UK law enforcement workloads. Our UK law enforcement customers who require PASF can continue to run their applications in the PASF-accredited Europe (London) Region in confidence.
The PASF is a long-established assurance process, used by UK law enforcement, as a method for assuring the security of facilities such as data centers or other locations that house critical business applications that process or hold police data. PASF consists of a control set of security requirements, an on-site inspection, and an audit interview with representatives of the facility.
The Police Digital Service (PDS) confirmed the accreditation renewal for AWS on May 27, 2025. A confirmation letter can be found on AWS Artifact. The UK police force and law enforcement organizations can also obtain confirmation of the compliance status of AWS through the Police Digital Service.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
Reach out to your AWS account team if you have questions or feedback about PASF compliance.
If you have feedback about this post, submit comments in the Comments section below.
Smatch is a GPL-licensed
static-analysis tool for C that has a lot of specialized checks for the kernel. Smatch
has been used in the kernel for more than 20 years; Dan
Carpenter, its primary author, decided last year that some details of its plugin system
were due for a rewrite. He spoke at Linaro Connect 2025 about his work on
Smatch, the changes to its implementation, and how those changes enabled him to easily
add additional checks for locking bugs in the kernel.
The “Local Mess” GitHub
repository is dedicated to the disclosure of an Android tracking
exploit used by (at least) Meta and Yandex.
While there are subtle differences in the way Meta and Yandex
bridge web and mobile contexts and identifiers, both of them
essentially misuse the unvetted access to localhost sockets. The
Android OS allows any installed app with the INTERNET permission to
open a listening socket on the loopback interface
(127.0.0.1). Browsers running on the same device also access this
interface without user consent or platform mediation. This allows
JavaScript embedded on web pages to communicate with native Android
apps and share identifiers and browsing habits, bridging ephemeral
web identifiers to long-lived mobile app IDs using standard Web
APIs.
This backdoor, the use of which has evidently stopped since its disclosure,
allow tracking of users across sites regardless of cookie policies or use of
incognito browser modes.
We’ve recently added support for the FinalizationRegistry API in Cloudflare Workers. This API allows developers to request a callback when a JavaScript object is garbage-collected, a feature that can be particularly relevant for managing external resources, such as memory allocated by WebAssembly (Wasm). However, despite its availability, our general advice is: avoid using it directly in most scenarios.
Our decision to add FinalizationRegistry — while still cautioning against using it — opens up a bigger conversation: how memory management works when JavaScript and WebAssembly share the same runtime. This is becoming more common in high-performance web apps, and getting it wrong can lead to memory leaks, out-of-memory errors, and performance issues, especially in resource-constrained environments like Cloudflare Workers.
In this post, we’ll look at how JavaScript and Wasm handle memory differently, why that difference matters, and what FinalizationRegistry is actually useful for. We’ll also explain its limitations, particularly around timing and predictability, walk through why we decided to support it, and how we’ve made it safer to use. Finally, we’ll talk about how newer JavaScript language features offer a more reliable and structured approach to solving these problems.
Memory management 101
JavaScript
JavaScript relies on automatic memory management through a process called garbage collection. This means developers do not need to worry about freeing allocated memory, or lifetimes. The garbage collector identifies and reclaims memory occupied by objects that are no longer needed by the program (that is, garbage). This helps prevent memory leaks and simplifies memory management for developers.
function greet() {
  let name = "Alice";         // String is allocated in memory
  console.log("Hello, " + name);
}                             // 'name' goes out of scope

greet();
// JavaScript automatically frees allocated memory at some point in future
WebAssembly
WebAssembly (Wasm) is an assembly-like instruction format designed to run high-performance applications on the web. While it initially gained prominence in web browsers, Wasm is also highly effective on the server side. At Cloudflare, we leverage Wasm to enable users to run code written in a variety of programming languages, such as Rust and Python, directly within our V8 isolates, offering both performance and versatility.
Wasm runtimes are designed to be simple stack machines, and lack built-in garbage collectors. This necessitates manual memory management (allocation and deallocation of memory used by Wasm code), making it an ideal compilation target for languages like Rust and C++ that handle their own memory.
Wasm modules operate on linear memory: a resizable block of raw bytes, which JavaScript views as an ArrayBuffer. This memory is organized in 64 KB pages, and its initial size is defined when the module is compiled or loaded. Wasm code interacts with this memory using 32-bit offsets — integer values functioning as direct pointers that specify a byte offset from the start of its linear memory. This direct memory access model is crucial for Wasm’s high performance. The host environment (which in Cloudflare Workers is JavaScript) also shares this ArrayBuffer, reading and writing (often via TypedArrays) to enable vital data exchange between Wasm and JavaScript.
A core Wasm design is its secure sandbox. This confines Wasm code strictly to its own linear memory and explicitly declared imports from the host, preventing unauthorized memory access or system calls. Direct interaction with JavaScript objects is blocked; communication occurs through numeric values, function references, or operations on the shared ArrayBuffer. This strong isolation is vital for security, ensuring Wasm modules don’t interfere with the host or other application components, which is especially important in multi-tenant environments like Cloudflare Workers.
Bridging WebAssembly memory with JavaScript often involves writing low-level “glue” code to convert raw byte arrays from Wasm into usable JavaScript types. Doing this manually for every function or data structure is both tedious and error-prone. Fortunately, tools like wasm-bindgen and Emscripten (Embind) handle this interop automatically, generating the binding code needed to pass data cleanly between the two environments. We use these same tools under the hood — wasm-bindgen for Rust-based workers-rs projects, and Emscripten for Python Workers — to simplify integration and let developers focus on application logic rather than memory translation.
Interoperability
High-performance web apps often use JavaScript for interactive UIs and data fetching, while WebAssembly handles demanding operations like media processing and complex calculations for significant performance gains, allowing developers to maximize efficiency. Given the difference in memory management models, developers need to be careful when using WebAssembly memory in JavaScript.
For this example, we’ll use Rust to compile a WebAssembly module manually. Rust is a popular choice for WebAssembly because it offers precise control over memory and easy Wasm compilation using standard toolchains.
Rust
Here we have two simple functions. make_buffer creates a string and returns a raw pointer back to JavaScript. The function intentionally “forgets” the memory allocated so that it doesn’t get cleaned up after the function returns. free_buffer, on the other hand, expects the initial string reference handed back and frees the memory.
// Allocate a fresh byte buffer and hand the raw pointer + length to JS.
// *We intentionally “forget” the Vec so Rust will not free it right away;
//   JS now owns it and must call `free_buffer` later.*
#[no_mangle]
pub extern "C" fn make_buffer(out_len: *mut usize) -> *mut u8 {
    let mut data = b"Hello from Rust".to_vec();
    let ptr = data.as_mut_ptr();
    let len  = data.len();

    unsafe { *out_len = len };

    std::mem::forget(data);
    return ptr;
}

/// Counterpart that **must** be called by JS to avoid a leak.
#[no_mangle]
pub unsafe extern "C" fn free_buffer(ptr: *mut u8, len: usize) {
    let _ = Vec::from_raw_parts(ptr, len, len);
}
JavaScript
Back in JavaScript land, we’ll call these Wasm functions and output them using console.log. This is a common pattern in Wasm-based applications since WebAssembly doesn’t have direct access to Web APIs, and rely on a JavaScript “glue” to interface with the outer world in order to do anything useful.
const { instance } = await WebAssembly.instantiate(WasmBytes, {});

const { memory, make_buffer, free_buffer } = instance.exports;

//  Use the Rust functions
const lenPtr = 0;                 // scratch word in Wasm memory
const ptr = make_buffer(lenPtr);

const len = new DataView(memory.buffer).getUint32(lenPtr, true);
const data = new Uint8Array(memory.buffer, ptr, len);

console.log(new TextDecoder().decode(data)); // “Hello from Rust”

free_buffer(ptr, len); // free_buffer must be called to prevent memory leaks
You can find all code samples along with setup instructions here.
As you can see, working with Wasm memory from JavaScript requires care, as it introduces the risk of memory leaks if allocated memory isn’t properly released. JavaScript developers are often unfamiliar with manual memory management, and it’s easy to forget returning memory to WebAssembly after use. This can become especially tricky when Wasm-allocated data is passed into JavaScript libraries, making ownership and lifetime harder to track.
While occasional leaks may not cause immediate issues, over time they can lead to increased memory usage and degrade performance, particularly in memory-constrained environments like Cloudflare Workers.
FinalizationRegistry
FinalizationRegistry, introduced as part of the TC-39 WeakRef proposal, is a JavaScript API which lets you run “finalizers” (aka cleanup callbacks) when an object gets garbage-collected. Let’s look at a simple example to demonstrate the API:
const my_registry = new FinalizationRegistry((obj) => { console.log("Cleaned up: " + obj); });

{
  let temporary = { key: "value" };
  // Register this object in our FinalizationRegistry -- the second argument,
  // "temporary", will be passed to our callback as its obj parameter
  my_registry.register(temporary, "temporary");
}

// At some point in the future when temporary object gets garbage collected, we'll see "Cleaned up: temporary" in our logs.
Let’s see how we can use this API in our Wasm-based application:
const { instance } = await WebAssembly.instantiate(WasmBytes, {});

const { memory, make_buffer, free_buffer } = instance.exports;

// FinalizationRegistry would be responsible for returning memory back to Wasm
const cleanupFr = new FinalizationRegistry(({ ptr, len }) => {
  free_buffer(ptr, len);
});

//  Use the Rust functions
const lenPtr = 0;                 // scratch word in Wasm memory
const ptr = make_buffer(lenPtr);

const len = new DataView(memory.buffer).getUint32(lenPtr, true);
const data = new Uint8Array(memory.buffer, ptr, len);

// Register the data buffer in our FinalizationRegistry so that it gets cleaned up automatically
cleanupFr.register(data, { ptr, len });

console.log(new TextDecoder().decode(data));   // → “Hello from Rust”

// No need to manually call free_buffer, FinalizationRegistry will do this for us
We can use a FinalizationRegistry to manage any object borrowed from WebAssembly by registering it with a finalizer that calls the appropriate free function. This is the same approach used by wasm-bindgen. It shifts the burden of manual cleanup away from the JavaScript developer and delegates it to the JavaScript garbage collector. However, in practice, things aren’t quite that simple.
Inherent issues with FinalizationRegistry
There is a fundamental issue with FinalizationRegistry: garbage collection is non-deterministic, and may clean up your unused memory at some arbitrary point in the future. In some cases, garbage collection might not even run and your “finalizers” will never be triggered.
“A conforming JavaScript implementation, even one that does garbage collection, is not required to call cleanup callbacks. When and whether it does so is entirely down to the implementation of the JavaScript engine. When a registered object is reclaimed, any cleanup callbacks for it may be called then, or some time later, or not at all.”
Even Emscripten mentions this in their documentation: “… finalizers are not guaranteed to be called, and even if they are, there are no guarantees about their timing or order of execution, which makes them unsuitable for general RAII-style resource management.”
Given their non-deterministic nature, developers seldom use finalizers for any essential program logic. Treat them as a last-ditch safety net, not as a primary cleanup mechanism — explicit, deterministic teardown logic is almost always safer, faster, and easier to reason about.
Enabling FinalizationRegistry in Workers
Given its non-deterministic nature and limited early adoption, we initially disabled the FinalizationRegistry API in our runtime. However, as usage of Wasm-based Workers grew — particularly among high-traffic customers — we began to see new demands emerge. One such customer was running an extremely high requests per second (RPS) workload using WebAssembly, and needed tight control over memory to sustain massive traffic spikes without degradation. This highlighted a gap in our memory management capabilities, especially in cases where manual cleanup wasn’t always feasible or reliable. As a result, we re-evaluated our stance and began exploring the challenges and trade-offs of enabling FinalizationRegistry within the Workers environment, despite its known limitations.
Preventing footguns with safe defaults
Because this API could be misused and cause unpredictable results for our customers, we’ve added a few safeguards. Most importantly, cleanup callbacks are run without an active async context, which means they cannot perform any I/O. This includes sending events to a tail Worker, logging metrics, or making fetch requests.
While this might sound limiting, it’s very intentional. Finalization callbacks are meant for cleanup — especially for releasing WebAssembly memory — not for triggering side effects. If we allowed I/O here, developers might (accidentally) rely on finalizers to perform critical logic that depends on when garbage collection happens. That timing is non-deterministic and outside your control, which could lead to flaky, hard-to-debug behavior.
We don’t have full control over when V8’s garbage collector performs cleanup, but V8 does let us nudge the timing of finalizer execution. Like Node and Deno, Workers queue FinalizationRegistry jobs only after the microtask queue has drained, so each cleanup batch slips into the quiet slots between I/O phases of the event loop.
Security concerns
The Cloudflare Workers runtime is specifically engineered to prevent side-channel attacks in a multi-tenant environment. Prior to enabling the FinalizationRegistry API, we did a thorough analysis to assess its impact on our security model and determine the necessity of additional safeguards. The non-deterministic nature of FinalizationRegistry raised concerns about potential information leaks leading to Spectre-like vulnerabilities, particularly regarding the possibility of exploiting the garbage collector (GC) as a confused deputy or using it to create a timer.
GC as confused deputy
One concern was whether the garbage collector (GC) could act as a confused deputy — a security antipattern where a privileged component is tricked into misusing its authority on behalf of untrusted code. In theory, a clever attacker could try to exploit the GC’s ability to access internal object lifetimes and memory behavior in order to infer or manipulate sensitive information across isolation boundaries.
However, our analysis indicated that the V8 GC is effectively contained and not exposed to confused deputy risks within the runtime. This is attributed to our existing threat models and security measures, such as the isolation of user code, where the V8 Isolate serves as the primary security boundary. Furthermore, even though FinalizationRegistry involves some internal GC mechanics, the callbacks themselves execute in the same isolate that registered them — never across isolates — ensuring isolation remains intact.
GC as timer
We also evaluated the possibility of using FinalizationRegistry as a high-resolution timing mechanism — a common vector in side-channel attacks like Spectre. The concern here is that an attacker could schedule object finalization in a way that indirectly leaks information via the timing of callbacks.
In practice, though, the resolution of such a “GC timer” is low and highly variable, offering poor reliability for side-channel attacks. Additionally, we control when finalizer callbacks are scheduled — delaying them until after the microtask queue has drained — giving us an extra layer of control to limit timing precision and reduce risk.
Following a review with our security research team, we determined that our existing security model is sufficient to support this API.
Predictable cleanups?
JavaScript’s Explicit Resource Management proposal introduces a deterministic approach to handle resources needing manual cleanup, such as file handles, network connections, or database sessions. Drawing inspiration from constructs like C#’s using and Python’s with, this proposal introduces the using and await using syntax. This new syntax guarantees that objects adhering to a specific cleanup protocol are automatically disposed of when they are no longer within their scope.
Let’s look at a simple example to understand it a bit better.
class MyResource {
  [Symbol.dispose]() {
    console.log("Resource cleaned up!");
  }

  use() {
    console.log("Using the resource...");
  }
}

{
  using res = new MyResource();
  res.use();
} // When this block ends, Symbol.dispose is called automatically (and deterministically).
The proposal also includes additional features that offer finer control over when dispose methods are called. But at a high level, it provides a much-needed, deterministic way to manage resource cleanup. Let’s now update our earlier WebAssembly-based example to take advantage of this new mechanism instead of relying on FinalizationRegistry:
const { instance } = await WebAssembly.instantiate(WasmBytes, {});
const { memory, make_buffer, free_buffer } = instance.exports;

class WasmBuffer {
  constructor(ptr, len) {
    this.ptr = ptr;
    this.len = len;
  }

  [Symbol.dispose]() {
    free_buffer(this.ptr, this.len);
  }
}

{
  const lenPtr = 0;
  const ptr = make_buffer(lenPtr);
  const len = new DataView(memory.buffer).getUint32(lenPtr, true);

  using buf = new WasmBuffer(ptr, len);

  const data = new Uint8Array(memory.buffer, ptr, len);
  console.log(new TextDecoder().decode(data));  // → “Hello from Rust”
} // Symbol.dispose or free_buffer gets called deterministically here
Explicit Resource Management provides a more dependable way to clean up resources than FinalizationRegistry, as it runs cleanup logic — such as calling free_buffer in WasmBuffer via [Symbol.dispose]() and the using syntax — deterministically, rather than relying on the garbage collector’s unpredictable timing. This makes it a more reliable choice for managing critical resources, especially memory.
Future
Emscripten already makes use of Explicit Resource Management for handling Wasm memory, using FinalizationRegistry as a last resort, while wasm-bindgen supports it in experimental mode. The proposal has seen growing adoption across the ecosystem and was recently conditionally advanced to Stage 4 in the TC39 process, meaning it’ll soon officially be part of the JavaScript language standard. This reflects a broader shift toward more predictable and structured memory cleanup in WebAssembly applications.
We recently added support for this feature in Cloudflare Workers as well, enabling developers to take advantage of deterministic resource cleanup in edge environments. As support for the feature matures, it’s likely to become a standard practice for managing linear memory safely and reliably.
FinalizationRegistry: still not dead yet?
Explicit Resource Management brings much-needed structure and predictability to resource cleanup in WebAssembly and JavaScript interop applications, but it doesn’t make FinalizationRegistry obsolete. There are still important use cases, particularly when a Wasm-allocated object’s lifecycle is out of your hands or when explicit disposal isn’t practical. In scenarios involving third-party libraries, dynamic lifecycles, or integration layers that don’t follow using patterns, FinalizationRegistry remains a valuable fallback to prevent memory leaks.
Looking ahead, a hybrid approach will likely become the standard in Wasm-JavaScript applications. Developers can use ERM for deterministic cleanup of Wasm memory and other resources, while relying on FinalizationRegistry as a safety net when full control isn’t possible. Together, they offer a more reliable and flexible foundation for managing memory across the JavaScript and WebAssembly boundary.
Чавдар Парушев: Да си призная, за себе си и до момента не мога да реша дали Джошуа Стивънсън е искрено каещ се грешник, месеци след като изиграх „Киберпънк“. Той несъмнено може да бъде такъв. Но в същото време поведението му може да бъде осмислено и като една голяма поза, едно голямо премятане на всичко и всички.
Джошуа Стивънсън е осъден на смърт престъпник без право на помилване. Няма контрол над това. Ще бъде екзекутиран със сигурност. Може обаче да промени формата на екзекуцията си от, да кажем, смъртоносна инжекция на разпъване на кръст. Защо? При първата форма би умрял бързо и безболезнено, но и безименно, безследно. А ако изиграе каещия се грешник и го направи добре, ако превърне екзекуцията си в танц на ума, ще постигне въжделената цел на всеки наемник от града (В. включително) – да умре като легенда с гръм и трясък. Ще остави своята следа, ще накара всички да го запомнят, щат – не щат. Потенциално милиони ще съпреживяват живота в последните му мигове. Ще гледат през неговите очи, ще кървят с неговите рани, ще издишат последния му дъх. Убиецът и измамникът ще изиграе всички като за последно, за да го запомнят като светец.
Тъкмо „Грешника“ ме постави като играч в ситуация на лудонаративен дисонанс. Историята започва с приемането на поръчение за убийството на Джошуа Стивънсън. Задача, която се чудех дали ще трябва да изпълня, докато се движех към правилното място в играта. Бях си поставил за цел да играя с несмъртоносни оръжия, които зашеметяват, без да убиват. За разлика от кажи-речи почти всички други заглавия, „Киберпънк“позволява такова пацифистко проиграване в по-голямата си част. От друга страна, в случай че играчът избере да не убие Джошуа, умира поръчителят.
Ако подобно на Миглена също мога да кажа, че изиграх „Киберпънк“ в пълен прехлас, то е заради това, че играта поставя сериозни въпроси, без да бърза да им отговаря. Парадоксално или не, удоволствието от нея е толкова по-голямо, колкото повече тя не се изчерпва единствено с лудическото удоволствие от играенето. Един от водещите такива въпроси според мен е кой и какво е Джони Сребърната ръка.
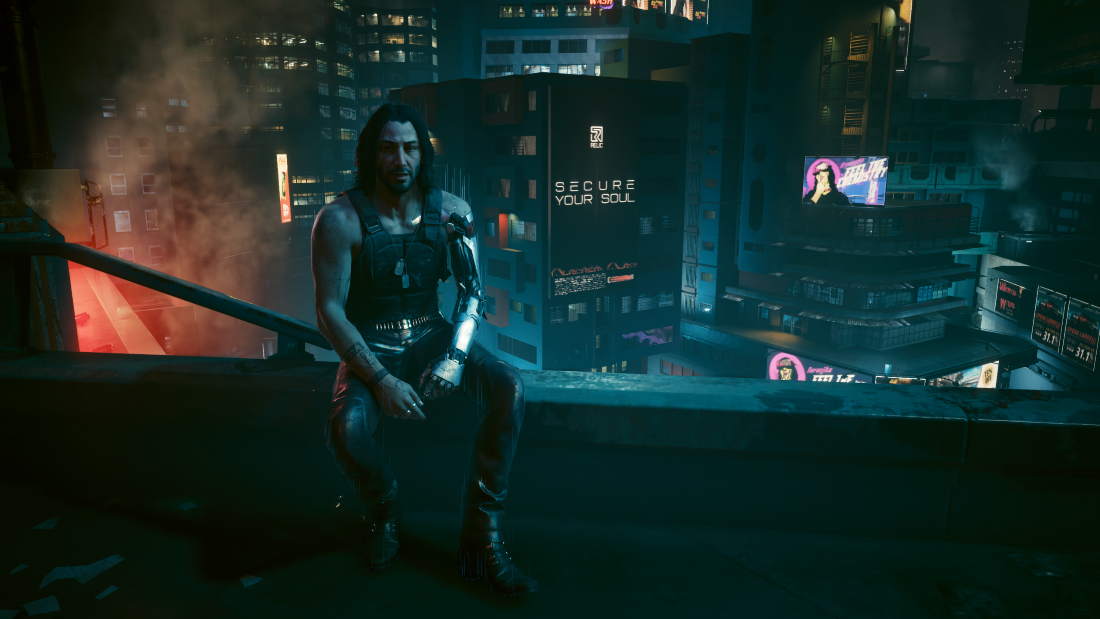
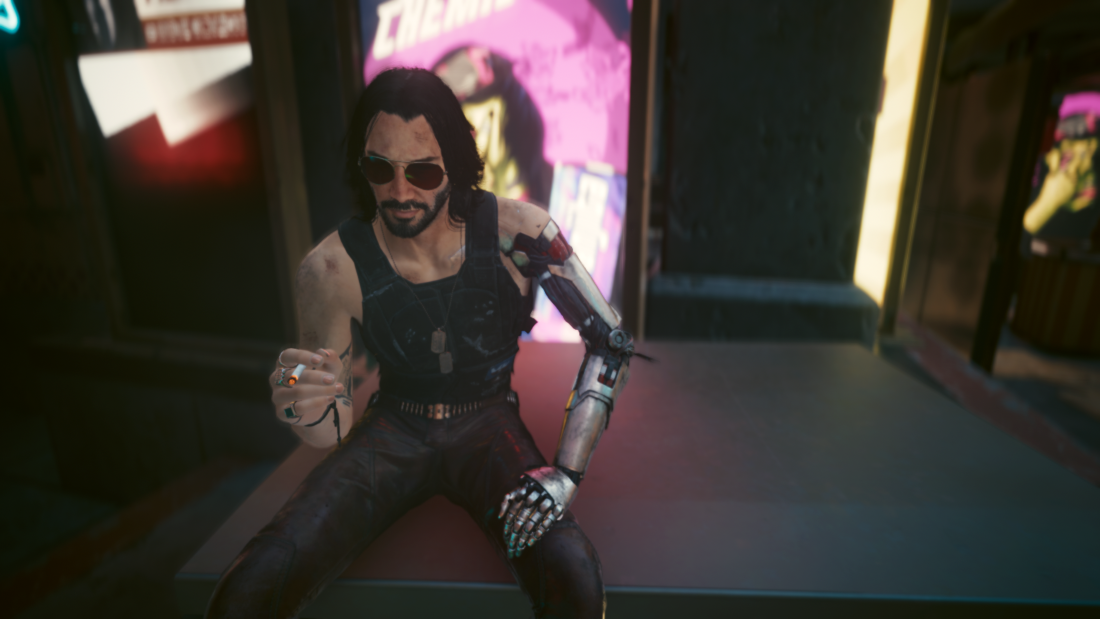
Кадри от „Киберпънк“
В плана на играта Джони е пълен невронен запис на рокаджия бунтар, подобаващо циничен, нарцистичен, изживял своя смъртоносен и бляскав миг на слава в терористичен жест на съпротива срещу големите корпорации петдесет години по-рано. В игровото настояще Джони е дигитално копие на себе си, записан върху експериментален биочип, имплантиран в главата на В. (персонажа аватар на играча в „Киберпънк“). Джони е „прожектиран“ в главата и мислите на В. Но той е „прожектиран“ и върху тялото и генетиката на В. в процес на бавно превземане или пренаписване на психиката, както го определи Еньо. Един непредвиден полеви тест на бета-версия на технология за безсмъртие, която би позволила на съзнанието да надживява тленността на първородното си тяло и да заживява в нови.
Откъдето и да бъде погледнат, този образ на Джони сблъсква перспективи и явява важни напрежения и размивания на основополагащи граници (като тази между органично и неорганично, между човек и машина). Джони е самият ръб на перпендикулярно засрещане на равнините на човешкото и машинното. Засрещане, в което тези равнини се събират, разделят, проникват, разсичат, разполовяват и залепват една за друга. Двойният образ на Джони-В. е впечатляващо сгъстен и богат на смисли. Ще опитам да очертая някои без претенции за изчерпателност.
Да започнем от живия, органичен Джони отпреди настоящето в играта. Органичен, но не съвсем. Персонажът има механична протеза от сребрист метал вместо лява ръка, откъдето и прякорът му Сребърната ръка. В плана на разказа тази метална ръка изглежда набавена на персонажа, за да го направи лесно открояващ се, лесно запомнящ се. Да бъде основа на неговия „бранд“. Да формира движение от почитатели, които да се идентифицират с него (и идентифицирайки се, да се самооразличават), за да удовлетворяват собствените си идентичностни потребности. Сякаш металните жици на електрическата китара (най-често изработвани от сплав на алуминий, никел и кобалт, също сребристи на цвят) са се издължили в ръка за Джони. Сякаш чрез металната ръка на Джони китарата и музиката се сливат. Една почти кентаврическа фигура на човек-китара, фигура на човек-изкуство-бунт (рок музика все пак).
В същото време тази сребърна ръка за Джони е напълно функционално равностойна на органичната му. Тя е протеза, която позволява на персонажа да свири неподражаемо и виртуозно (а също така да борави без неудобство с пистолети, взривни устройства). Рокът на Джони се ражда колкото изпод органичната, толкова и изпод металната му ръка. Още преди персонажът да бъде превърнат в дигитално копие, заредено в органичен ум, това, което прави Джони Джони, е частично машина, снадена върху органиката му.
Същевременно наративът на играта поставя въпроса, без да отговаря нито еднозначно, нито окончателно дали дигиталният Джони е идентичен на органичния Джони. Продължава ли той да живее в машината под някаква нова сложна форма, или това, което се явява от машината като призрак на миналото, е симулация, ерзац човек, само подобен на действителния.
Да си припомним, че мотивът за човек и човешко съзнание на запис на магнетофонна лента или друг носител далеч не е нов в научната фантастика. Такива ерзац човеци на запис са мъртвите линии в киберпънк романите на Уилям Гибсън от 70-те и 80-те. Мотивът е водещ за „Юбик“ на Филип Дик от 1969-та. Присъства в разкази и произведения на Роджър Зелазни (в „Създания от мрак и светлина“ например победените врагове са превърнати в мислещи вещи – килими бюра, преспапиета – за злорада наслада на победителя си). Същият този мотив продължава да бъде важен и за актуални автори, като Нийл Стивънсън (особено в „Падение, или Додж в ада“, публикувана през 2019 г.). За Стивънсън дигиталните мъртви пазят ценностите и стремежите на органичния си живот, но са новоформиращи се и различни личности. За Гибсън мъртвите линии са по-скоро набор от логаритмично управлявани реакции, снети от съзнанието на някога жив човек, отколкото действително мислещи същества. Полуживотът в „Юбик“, както и в „Киберпънк“ поддържа въпроса отговорен, доколкото той е смислово по-важен именно като въпрос, отколкото като който и да е от възможните си отговори.
Играчът, поемащ контрола над В., е свободен да осмисля Джони, както реши – като мъртва линия, като полуживот, като пълноценно и равностойно на органичното дигитално съществуване. При определен стил на игра Джони търпи развитие, променя се, израства. Нарцистичният циник, пълно говедо с жените в живота си, който се интересува само от собствената си музика бунт (пък всичко останало да го гази валяк), достига до готовност да жертва себе си за В., да бъде заличен, за да може В. да живее. Но дори и при такова проиграване на историята това развитие може да се дължи колкото на втория шанс, получен от Джони, който съжителства в тялото на В. и наблюдава как някой друг постъпва различно и доживява до по-голяма личностна зрялост, толкова и на пряко пренаписване на „софтуера“ Джони от страна на органичния В. (влиянието и психическото пренаписване върви и в двете посоки между Джони и В.).
За да завърши, за да изиграе играта докрай, играчът трябва да вземе решение, да избере какво да прави с Джони – да му позволи ли да живее, жертвайки В., или не. А за да реши, трябва да си отговори на въпросите кой и какво е Джони. Дали това е духът на миналото, искрицата бунт, изразена в музика, която трябва да оживее отново, или не. Дали това е експеримент по машинно безсмъртие, на който трябва да се даде път, или пък да се спре; да му се позволи да бъде успешен или да бъде провален. Дали Джони е само дигитален запис, софтуер, призракът на машината, на машинно движения град и логаритмично подчиненото съществуване, на което не трябва да се позволява да пренаписва органичното. Не трябва да му се позволява да се възпроизвежда отново и отново върху и за сметка на органичното, отнемайки правото на новото и различното, на бъдещето (персонифицирано в лицето на младежа В.) да бъде. В крайна сметка човек или машина е Джони, човек или машина е В.? Кой трябва да остане, кой трябва да си отиде, кой може и трябва да бъде?
Този избор, осмислян или не, е предоставен на всеки играч и на всяко проиграване. Смятам, че това е едно (без да е единственото) от сериозните достижения на „Киберпънк“, които трябва да се признаят на играта. Достижение, заради което тя заслужава по-задълбочено внимание, включително и множество преигравания. Играта кара играча да прави избори в това сложно засрещане на размиващи се граници между човешкото и машинното. И това е разгърнато по далеч по-задълбочен и пълнокръвен начин в сравнение с предходни опити за проиграване на тази дилема в други игри. Помним колко по-повърхностно прави това „Ефектът на масата“ в третата си част например.
Миглена Николчина: Във финала на „Шест лица търсят автор“, пиеса от Луиджи Пирандело, играещите на сцената – наричам ги така, защото част от актьорите играят, че са… актьори, а друга част играят „измислени“ персонажи, които „не играят“, те са „себе си“ и затова претендират, че са по-истински от „актьорите“, – та всички те започват да крещят по повод смъртта на един от персонажите: „Измислица! Действителност!“ (на български има превод като „Преструвка! Действителност!“ А на италиански е Finzione! Realtà! – тоест можем да кажем и „Фикция! Действителност!“). Някои крещят едното, други другото, трети и двете, всичко това щедро поръсено с удивителни и въпросителни. Грешника е в тази ситуация. Колкото и да се преструва, той умира, смъртта му е истинска… в един виртуален свят. Тоест в два виртуални свята – вътрешния на играта, където смъртта му ще се заснеме в „танц“, и външния, нашия, на играчите. Тази смърт е едното, другото и двете заедно. Така този разказ притчово удвоява големия разказ на „Киберпънк“, в чиято рамка се появява и извежда жертвата като сърцевина на смисъла му.
В големия разказ жертвата грешник е Джони, чийто танц нашият аватар (и ние с него) ще трябва да изживее в тази амалгама на илюзия и действителност, която е принципно изкуството. Аватарът е назован с инициала V., което се произнася Ви – може би има други обяснения, но ще отбележа, че на полски така се произнася вие – тоест ние сме вие – за кого? За Джони? За играта и нейните създатели, които впрочем са се вписали в картата като улични продавачи на „танци“? За ние-то на музика и бунт, на ето ни и нас, това сме ние, „Червените китари“, To właśnie my?
И тук ще се върна към темата за дисонанса. Аз играех като жена и трябва да си призная, че първото изскачане от мене на Джони, този демоничен Хийтклиф с външността на Киану Рийвс, направо ме отнесе. Самото двойничество на персонажа ми се струва по-работещо, ако аватарът е жена – психологическата динамика става друга. Еньо вече обрисува аватара като наемник, който се бори да оцелее, но е постоянно „центробежно“ разсейван от съблазните на града. Този наемник се оказва чипиран – обладан, раздвоен – с Джони: музикант, гений, бунтар, циник, развалина, самоубиец – всичко това едновременно. Но дори в ексцесите – или може би тъкмо в тях – на алкохол, секс и прочее опиянения той е несводим до търсенето на оцеляване. И ето го лудонаративния дисонанс, вграден в самия раздвоен герой – оцеляване на всяка цена (сделки, апартаменти, коли, секс и прочее разсейващи сюжети) или битка, терор, взрив, самоубийство (основния сюжет).
И двете страни са страни на един невъзможен бунт – с тази разлика, че в епохата на Джони все още са опитвали да се бунтуват, та било то с музика и дрога. Чипът „Джони“ е вклиняването на тази предишна епоха в деградиралите руини от онова, което се е получило от нея. И все пак внушението е, че невъзможният бунт е и необходим, а това означава, че той може да се случи само като останала напълно незабелязана или медийно тиражирана жертва: фикция, действителност.
(Следва продължение.)
В рубриката „Игромислие“ публикуваме разговори, в които се срещат, съпоставят и противопоставят различни гледни точки към многоизмерния, многожанров феномен на видеоигрите – не толкова като електронен спорт, колкото като нов синтез на изкуствата и като ново поле на общуване и социалност.
We’re thrilled to celebrate yet another incredible year of young people reaching for the stars, as the European Astro Pi Challenge 2024/25 draws to a close. Teams from across Europe and ESA Member States are now receiving their well-deserved certificates and data from the International Space Station (ISS). It’s been a truly inspiring year, showcasing the phenomenal talent and dedication of young coders and scientists.
The European Astro Pi Challenge is an ESA Education project run in collaboration with us here at the Raspberry Pi Foundation. It offers young people the amazing opportunity to conduct scientific investigations in space by writing computer programs that run on Raspberry Pi computers on board the ISS, called Astro Pis.
There‘s a lot to celebrate from this year’s Astro Pi, so let’s take a look at some of the highlights for each of our inspiring Missions: Mission Zero and Mission Space Lab.
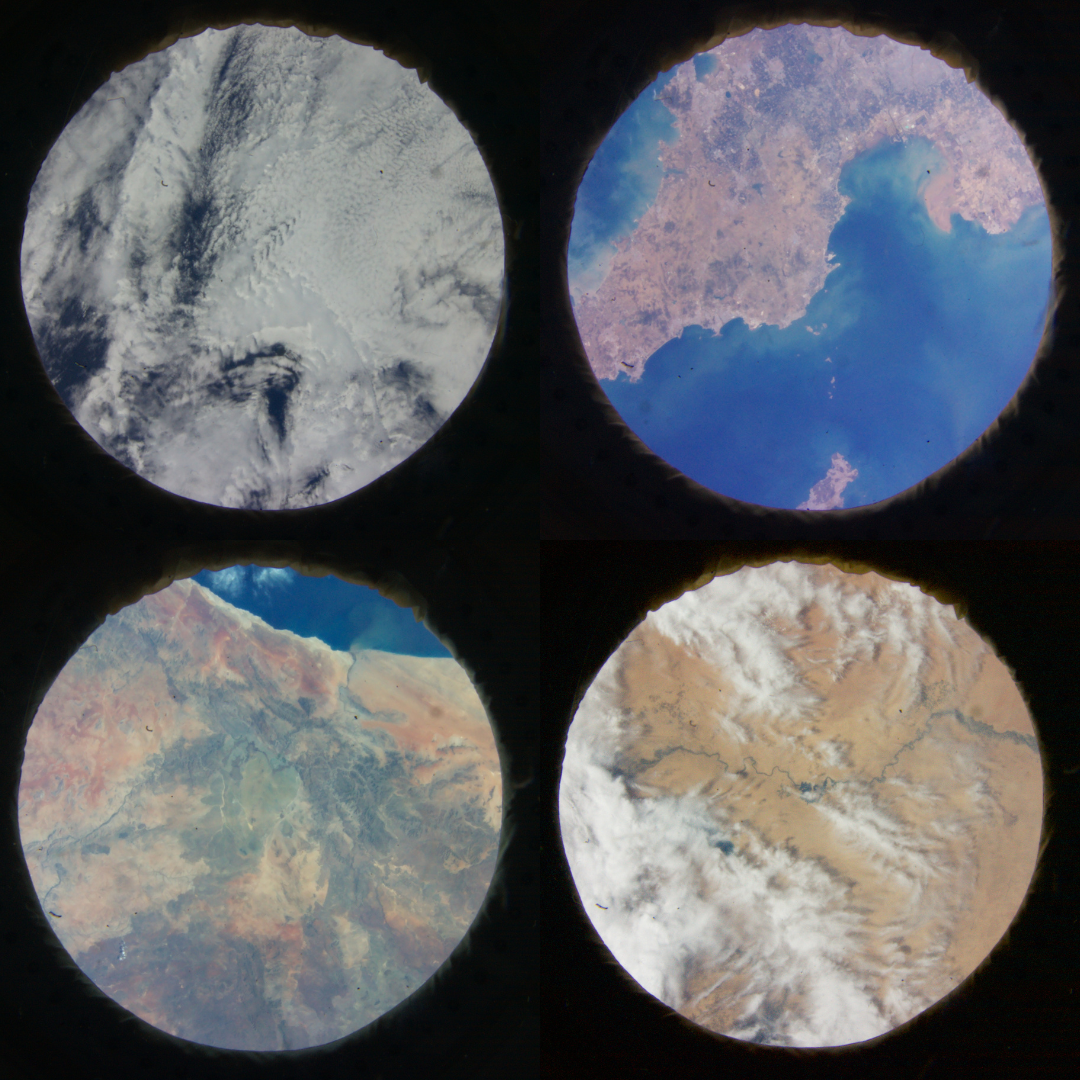
Figure 1: A selection of images taken by Mission Space Lab teams
Mission Zero: Inspiring coding, creativity, and inclusion
Mission Zero reached more young people than ever before in 2024/25, with 25,405 young people participating in 17,285 teams. After passing the rigorous testing and moderation processes, an amazing 17,109 teams (25,210 young people) were successful in getting their programs to run on the ISS.
One of the great things about Mission Zero is that we see a good gender balance in participation. This year, 44% of participants identified as “female” and 4% as “prefer to self-describe”, “prefer not to say”, or “other”. This means that Mission Zero has achieved a more balanced gender representation than is typically seen in computing subjects, where the ratio is around 20:80 girls to boys.
Mission Space Lab: More teams have their programs run in space
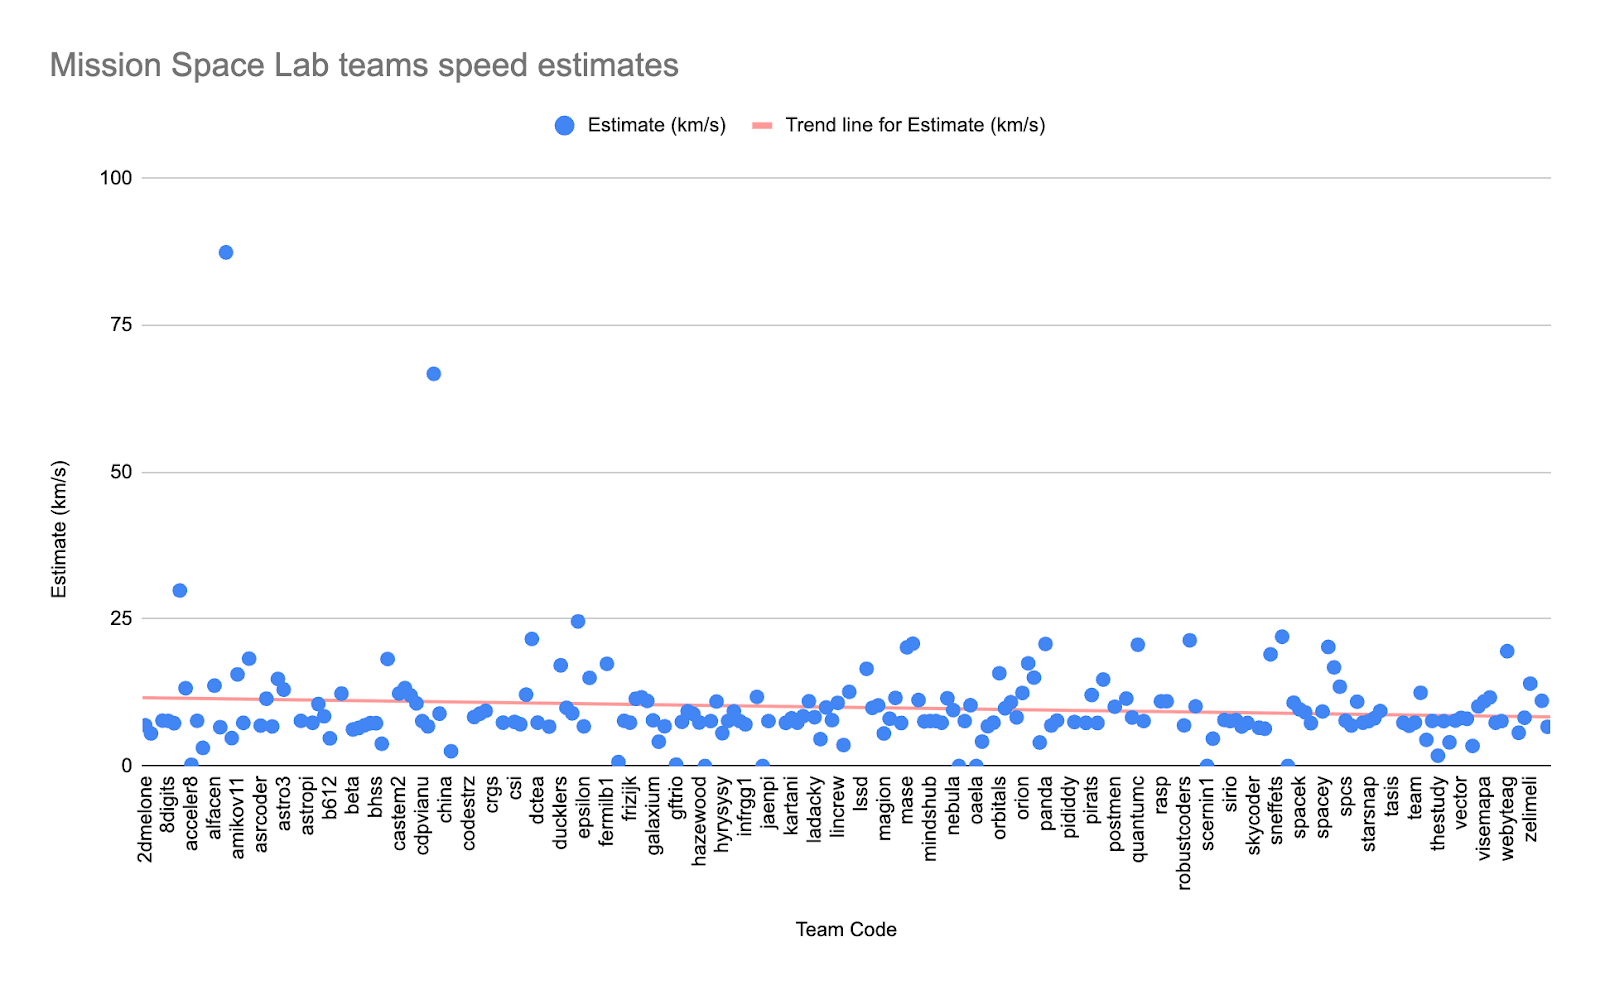
Mission Space Lab gives young people the opportunity to calculate the speed of the ISS in orbit using sensor and camera data collected from the Astro Pis on board the ISS. This year, 1859 young people in 552 teams participated in Mission Space Lab. Notably, 309 Mission Space Lab teams, or 95% of submissions, ran their programs on the ISS and are now analysing the data they collected. That’s 73 more teams achieving flight status than in 2023/24, and a total of 1084 young people receiving unique data sets from space and certificates.
Running a program in space is very different from testing it on the ground. It’s always interesting to see how well your program has performed and how accurate the final output is. Below, you can see a scatter graph of the team estimates produced by their programs. The actual speed of the ISS is no secret: it’s travelling about 7.67 kilometres per second. How have teams performed with the ISS speed task?
Figure 2: Mission Space Lab teams’ speed estimates graph
Inspiring and impactful
Another highlight from this year has been seeing how impactful participation can be for young people and mentors facilitating the activity. We receive lots of valuable feedback from the Astro Pi community each year, and it’s always heartwarming to hear what your experience has been and how we can improve the challenge. Here are a couple of quotes from the community who took part this year:
Mission Zero mentor: “Having their programs run in space really motivated them to take part because it was an exciting reward and something they wanted to talk about with their friends.”
Parent of a Mission Zero participant: “I was completely inexperienced in Python, but easily managed to help my 7-year-old.”
More Code Clubs participating in 2024/25
It has been great to see lots of Code Clubs taking part in Astro Pi this year, both for Mission Zero and Mission Space Lab. This year, 986 young people from 700 teams did Mission Zero at their Code Club: that’s double the number from 2023/24. Plus, 43 Mission Space Lab teams from Code Clubs took part. That’s 143 young people, or almost double the number compared to the year before.
We ran two code-alongs for the Code Club community this year, and it is encouraging to see increases for both missions. We will continue to support young people from all settings who want to take part in Astro Pi next year, whether it’s at school, Code Club, or other venues.
Conclusion
In summary, it’s been a great year for Astro Pi. We’ve reached lots of young people through the challenge, met many inspiring mentors, and seen some really positive trends. Plus, all the operations on the space station that make Astro Pi possible went smoothly: when you are running programs in space, that isn’t always the case!
None of it would have been possible without the tireless efforts of the teachers, mentors, and educators who help run Astro Pi in your communities. From everyone here at Mission Control, thank you.
If you’d like to tell us how we can provide more support to help you run Astro Pi, please email [email protected].
We’ll be back for more stellar space adventures in coding in September 2025.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.